Last week, I took some time off in York, England, often described as the most haunted city in the country. I wandered through the ruins of abbeys that have stood for nearly a thousand years, walked along medieval walls, and spent an evening on a ghost tour hearing stories passed down through centuries. There’s something grounding about standing in a place that has witnessed so much history. Now I’m back at my desk, and the contrast is hard to miss: those abbey stones have stood for a thousand years largely unchanged, while in the span of a single week away, the pace of technological change has moved forward yet again.
The ruins of Whitby Abbey in North Yorkshire. Stones that have seen a thousand years, while this week alone brought another wave of change.
Now, let’s get into this week’s AWS news.
Headlines On April 28, Matt Garman, CEO of AWS, Colleen Aubrey, SVP Amazon Applied AI Solutions, Julia White, CMO of AWS, and OpenAI leaders took the stage to share how customers are changing the way businesses operate with agents. The event brought a packed slate of announcements across Amazon Quick, Amazon Connect, and a deeper partnership with OpenAI. Here’s a roundup of the biggest announcements from the event.
Amazon Quick expands with a desktop app, new pricing plans, and visual asset generation – Amazon Quick is an AI assistant for work that connects to your apps, learns what matters to you, and takes action on your behalf. This week, Quick introduced a new desktop app (Preview) that keeps you connected to your local files, calendar, and communications without opening a browser. You can sign up within minutes using your personal email address or existing Google, Apple, Github, or Amazon credentials—no AWS account required. Quick can now generate polished documents, presentations, infographics, and images directly from the chat interface, and native integrations expand to include Google Workspace, Zoom, Airtable, Dropbox, and Microsoft Teams. A new Build custom apps with Quick capability (Preview) lets you create intelligent apps, dashboards, and web pages connected to the rest of your business using natural language.
Amazon Connect expands into four agentic AI solutions – Amazon Connect is expanding from a single product into a set of four agentic AI solutions designed to work within your existing workflows. Amazon Connect Decisions is a supply chain planning and intelligence solution that shifts teams from crisis management to proactive planning, combining 30 years of Amazon operational science with more than 25 specialized supply chain tools. Amazon Connect Talent (Preview) is an agentic AI hiring solution that delivers AI-led interviews, science-backed assessments, and consistent evaluation for talent acquisition leaders managing scaled hiring. Amazon Connect Customer, previously known as Amazon Connect, delivers personalized customer experiences across voice, chat, and digital channels, with new configuration capabilities that enable organizations to set up conversational AI in weeks rather than months. Amazon Connect Health delivers agentic patient verification, appointment management, patient insights, ambient documentation, and medical coding, giving patients faster access to care and clinicians more time to deliver it.
AWS and OpenAI expand their partnership across Amazon Bedrock – AWS and OpenAI are bringing the latest OpenAI models to Amazon Bedrock, launching Codex on Amazon Bedrock, and introducing Amazon Bedrock Managed Agents powered by OpenAI — all in limited preview. OpenAI models on Amazon Bedrock (Limited preview) brings the latest OpenAI models, including GPT-5.5 and GPT-5.4, to the Bedrock APIs you already use, with unified security, governance, and cost controls. No additional infrastructure to configure, no new security model to learn. Codex on Amazon Bedrock (Limited preview) lets you access the OpenAI coding agent within your existing AWS environments, authenticating with your AWS credentials, processing inference through Bedrock, and applying Codex usage toward your AWS cloud commitments. Codex on Bedrock is available through the Bedrock API, starting with the Codex CLI, the Codex desktop app, and a Visual Studio Code extension. Amazon Bedrock Managed Agents, powered by OpenAI (Limited preview) combines OpenAI frontier models with AWS infrastructure to build production-ready OpenAI-powered agents in the cloud, built with the OpenAI harness for faster execution, sharper reasoning, and reliable steering of long-running tasks.
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Amazon EC2 M8in and M8ib instances are now generally available – Powered by custom 6th-gen Intel Xeon Scalable processors and 6th-gen AWS Nitro cards, these instances deliver up to 43% higher performance over M6in and M6ib. M8in offers 600 Gbps network bandwidth, while M8ib delivers up to 300 Gbps EBS bandwidth. Available in US East (N. Virginia), US West (Oregon), Asia Pacific (Tokyo), and Europe (Spain).
Amazon EC2 R8in and R8ib instances are now generally available – Memory-optimized instances built on the same 6th-gen Intel Xeon Scalable processors and Nitro cards, with the same 600 Gbps network and 300 Gbps EBS bandwidth profiles. Well-suited for large commercial databases, data lakes, and in-memory databases such as SAP HANA. Available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Spain).
Amazon EC2 C8ine and M8ine instances are now generally available – Network-optimized instances offering up to 2.5x higher packet performance per vCPU and up to 2x higher network throughput for traffic through internet gateways compared to C6in and M6in. Designed for security and network virtual appliances including virtual firewalls, load balancers, and 5G UPF workloads. Available in US East (N. Virginia), US West (Oregon), and Asia Pacific (Tokyo) for C8ine; US East (N. Virginia) and US West (Oregon) for M8ine.
Amazon Bedrock AgentCore adds optimization capabilities (Preview) – AgentCore now offers recommendations, batch evaluations, and A/B tests to complete the observe-evaluate-improve loop for agents in production. Recommendations analyze production traces and evaluation outputs to propose optimized system prompts and tool descriptions, which you can validate with batch evaluations against pre-defined test cases or A/B tests against live traffic. Every recommendation requires your approval before it ships.
AWS Lambda adds support for Ruby 4.0 – Ruby 4.0, the latest LTS release, is available as a Lambda managed runtime and container base image. It includes support for Lambda advanced logging controls, including JSON structured logs, configurable logging levels, and target CloudWatch log group configuration. Available in all AWS Regions, including China Regions and AWS GovCloud (US).
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts and resources that you might find interesting:
Amazon Q Developer end-of-support announcement – Amazon Q Developer IDE plugins and paid subscriptions will reach end of support on April 30, 2027, giving customers 12 months to transition to Kiro. New signups will be blocked starting May 15, 2026, although existing subscriptions can continue to add users. Starting May 29, 2026, Opus 4.6 will no longer be available on Q Developer Pro; Opus 4.5 and other existing models remain available, and the latest coding models including Opus 4.7 are available exclusively on Kiro. Amazon Q Developer in the AWS Management Console and first-party AWS experiences (documentation, mobile app, Slack, and Microsoft Teams) are not affected.
AWS 10,000 AIdeas Competition: Meet the Winners – AWS announced the 20 winners of the 10,000 AIdeas Competition, a global challenge where builders submitted AI applications built entirely with Kiro and the AWS Free Tier, with submissions from 115 countries narrowed down through four rounds of evaluation and two rounds of community voting. Winners span Global Champions, Regional Champions, Innovation Awards, and Creative Track categories, with cash prizes and AWS credits awarded across each tier.
AWS Student Builder Groups – AWS Cloud Clubs is evolving to AWS Student Builder Groups. The community now spans 600+ colleges and universities across 63 countries. Existing Cloud Club memberships, badges, and progress carry forward, and Cloud Club Captains become Group Leaders. Membership is open to any learner 18 or older. You can find a group near you on AWS Builder Center or apply to launch a new group on your campus.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
It’s only been a few weeks since Anthropic announced the Claude Mythos Preview model and launched Project Glasswing with AWS and other leading organizations. This has generated a lot of discussion about the future of cybersecurity and what the ever-increasing capabilities of foundation models mean to organizations.
As AWS CISO Amy Herzog pointed out in the Project Glasswing announcement, “At AWS, we build defenses before threats emerge, from our custom silicon up through the technology stack. Security isn’t a phase for us; it’s continuous and embedded in everything we do.”
While the discussion around the future of cybersecurity is important, the only thing we know for certain is that organizations need to be able to react quickly to the rapid changes AI is bringing to technology and business in general. And you can’t react quickly if your security fundamentals aren’t dialed in.
The security hygiene gap
It’s easy to assume you have the foundational security elements covered, or to overlook some completely. Basic security use cases like identity management, threat detection, vulnerability management, data protection, and network security can be inconsistently implemented across cloud environments. While AI is reshaping the security landscape, strong security fundamentals continue to be essential for every organization, regardless of size or industry.
These are the security basics that matter whether or not you’re adopting AI: patching consistently, enforcing least-privilege access, enabling logging and monitoring, encrypting data at rest and in transit, and reviewing security configurations regularly. When these fundamentals are in place, you’re better positioned to take advantage of AI-driven tools and respond to newly discovered vulnerabilities, wherever they come from.
While the concepts that drive security fundamentals are universal, implementing them in your environment is best done with an understanding of the context unique to your organization. That’s why we have a multitude of freely available materials—like the AWS Well-Architected Framework—that you can use to help ask the right questions and implement changes in your environment. We also offer programs like the Security Health Improvement Program (SHIP) to help you improve your security posture through prescriptive guidance and continuous improvement.
What is the Security Health Improvement Program (SHIP)?
SHIP is a no-cost program available to every AWS customer, regardless of support tier. SHIP provides a proven, data-driven methodology to:
Assess your current security posture using data from your AWS environment
Identify specific opportunities to improve across 10 core security use cases
Build a prioritized action plan tailored to your environment
Establish a mechanism for continuous security improvement
The program is led by AWS Solutions Architects and Technical Account Managers who take you through a personalized report, contextualize findings for your environment, and help you build a prioritized action plan.
Why SHIP matters in the AI era
Project Glasswing highlights an important shift: AI-powered tools are accelerating the pace of vulnerability discovery, which means organizations need to be prepared to assess and respond to findings and changing situations faster than before. In addition to external factors, as organizations adopt AI—whether deploying foundation models, building agentic workflows, or using AI-powered services—how they implement their security controls must change as well. A strong security foundation is what makes confident AI adoption possible.
Here’s how SHIP helps:
Address foundational security gaps proactively
SHIP uses a data-driven methodology to identify opportunities to improve and optimize across 10 core security use cases: threat detection, cloud security posture management, application security testing, configuration management, access governance, vulnerability management, application protection, network security, encryption, and secrets management. The program includes a SHIP assessment to identify critical security findings related to your current security posture, so your team can build a prioritized roadmap for improvement tailored to your environment.
Establish the security baseline AI workloads require
Before you deploy your first model on Amazon Bedrock or build agentic workflows with Amazon Bedrock AgentCore, you need confidence that your underlying infrastructure follows security best practices. SHIP uses actual data from your environment to provide prescriptive, specific guidance rather than generic security recommendations. This is especially relevant as AI-driven vulnerability discovery tools become more widely available: organizations with strong baselines will be able to act on new findings quickly and effectively.
Build a mechanism for continuous security improvement
As AI capabilities evolve, organizations benefit from having a repeatable process to assess and strengthen their security posture over time. SHIP establishes the methodology and mechanisms for your team to continuously assess, prioritize, and improve. By building this operational capability, you’re strengthening your organization’s ability to adapt and contributing to broader industry resilience. As the cybersecurity community integrates AI into defense strategies, SHIP helps you maintain foundational best practices so you can adopt these innovations effectively and with confidence.
Getting started is straightforward
SHIP is available today, at no cost, to every AWS customer. Here’s how to get started:
Talk to your AWS account team. Ask about scheduling a SHIP engagement, or request one directly on the SHIP page.
Attend a SHIPActivation Day. AWS regularly hosts hands-on workshops where you can run the SHIP assessment with AWS Solutions Architects and start building your improvement plan.
Explore the prescriptive guidance. Consult the AWS Well-Architected Framework – Security Lens for documentation, reference architectures, and implementation guides you can start using today.
Take the next step together
AWS is committed to being the most secure cloud, from our participation in Project Glasswing to the security embedded in every layer of our infrastructure. Security is a shared responsibility, and programs like SHIP give customers the tools, guidance, and support to strengthen their security foundations so they can build confidently, no matter what comes next.
Ready to improve your security posture? Contact your AWS account team to schedule a SHIP engagement, or visit the SHIP resources page to learn more.
Stay current with the latest serverless innovations that can improve your applications. In this 32nd quarterly recap, discover the most impactful AWS serverless launches, features, and resources from Q1 2026 that you might have missed.
In case you missed our last ICYMI, check out what happened in Q4 2025.
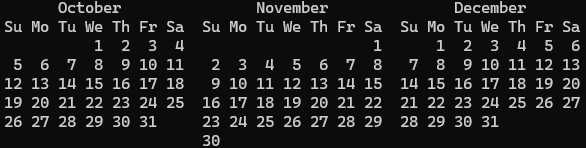
2026 Q1 calendar
Serverless with Mama J
Serverless with Mama J
If you really want to know whether you understand something, try explaining it to your mom!
That’s exactly what Eric Johnson did. His mom, everyone calls her Mama J, wanted to know what serverless actually means and why it matters. So he walked her through it: what servers do, why they’re a headache to manage, and how AWS Lambda lets you skip all that by running code only when it’s needed, scaling automatically, and charging you nothing when nobody’s using it.
AWS is providing a growing set of AI-powered tools to bring serverless expertise directly into your coding assistants. From Model Context Protocol (MCP) servers and Anthropic Claude plugins to Kiro Powers. These tools provide contextual guidance for architecture decisions, implementation patterns, and deployment automation across the full serverless development lifecycle.
For more information on the tools available, see the resources page.
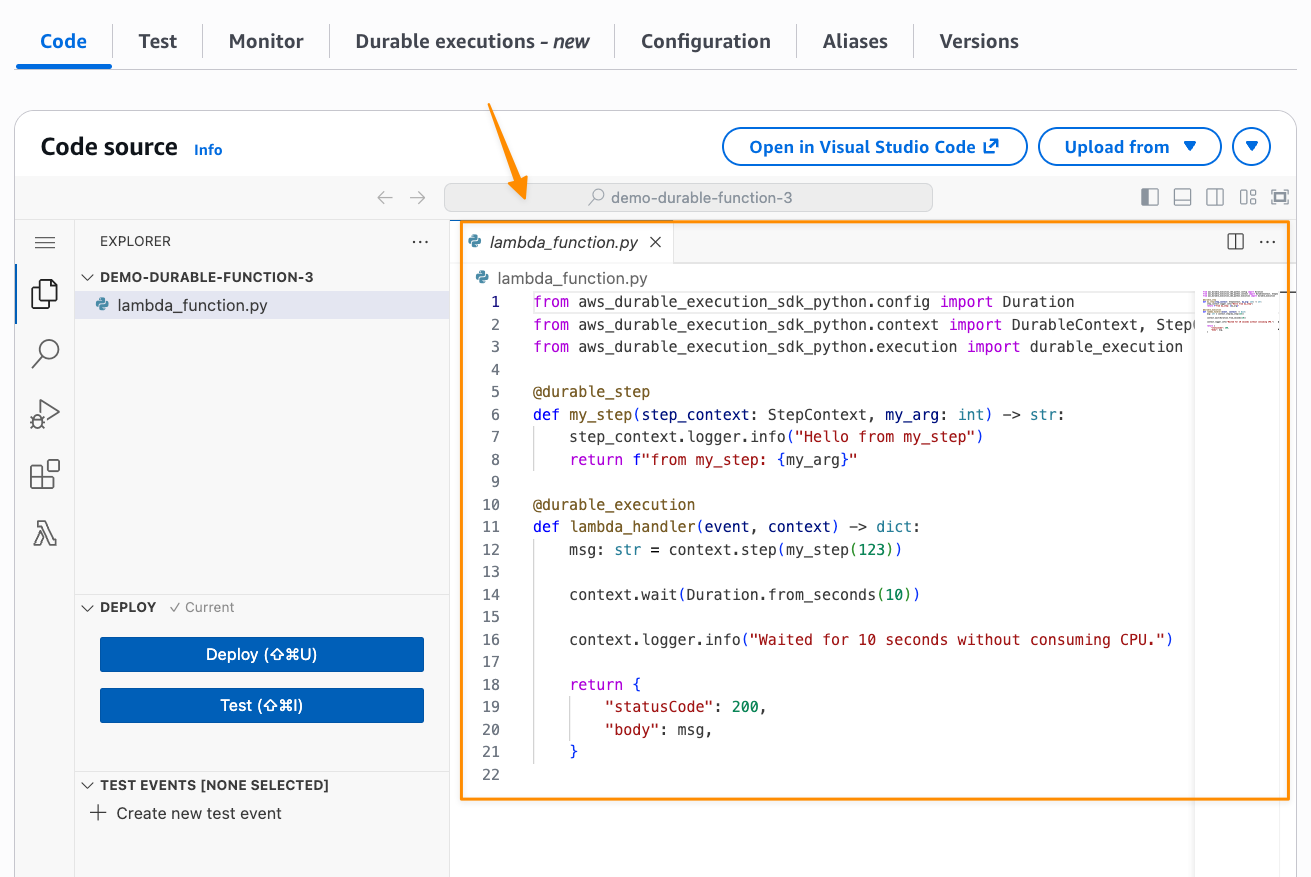
Build fault-tolerant, long-running applications using familiar programming patterns using AWS Lambdadurable functions. You can use Lambda durable functions to write multi-step workflows in your preferred programming language, using built-in methods that automatically handle progress checkpointing and error recovery. This can improve your architecture so that you can focus on your business logic and optimize costs by charging only for active compute time.
Eric Johnson has a new video deep dive showing how to upload videos and scan them with AI. Learn how to coordinate multiple AWS services like Amazon Rekognition and Amazon Transcribe, implement human-in-the-loop approval workflows, and crate a live dashboard for real-time updates.
Lambda now supports the .NET 10 runtime, including support for file-based apps. Developers can take advantage of the latest .NET 10 performance improvements, new language features, and improved startup times for Lambda functions.
You can now see Availability Zone (AZ) metadata in function execution environments. This allows you to determine the AZ ID (e.g., use1-az1) of the AZ your function is running in. This helps build functions that can make AZ-aware routing decisions, such as preferring same-AZ endpoints for downstream services to reduce cross-AZ latency. Operators can also implement AZ-aware resilience patterns like AZ-specific fault injection testing.
Payload size increase
AWS has increased the maximum payload size from 256 KB to 1 MB for a number of services such as asynchronous Lambda invocations, Amazon SQS, and Amazon EventBridge. This gives you more room to build and maintain context-rich event-driven systems and reduce the need for complex workarounds such as data chunking or external large object storage.
This blog post explores a real-world example using rich event context in agentic event-driven architectures
Amazon Bedrock AgentCore is the infrastructure layer for securely deploying and operating AI agents. It works with popular open source frameworks, including Strands Agents, LangGraph and CrewAI, giving you the flexibility to build with your preferred tools without vendor lock-in.
AgentCore Gateway now includes semantic tool search, so you can discover the right tool for a task using natural language queries instead of manually browsing a catalogue. It also adds custom KMS encryption, debugging messages, and resource tagging to give you stronger governance over tool integrations.
Policy in Bedrock AgentCore allows you to define precise boundaries on agent actions and run continuous quality monitoring. This helps you maintain predictable, auditable agent behavior in production without embedding guardrail logic inside each individual agent.
AgentCore Runtime now supports stateful MCP server features, allowing agents to maintain session context across tool calls for richer, more coherent multi-step interactions.
AWS Step Functions introduces an enhanced TestState API that enables API-based testing for validating workflows before deployment. The new API supports testing individual states in isolation or complete workflows end-to-end, making it easier to verify state machine logic without incurring runtime costs.
By integrating TestState API testing into CI/CD pipelines, you can validate workflow logic before deployment, reducing the risk of production issues. Find complete code examples and testing framework in the GitHub repository.
Amazon EventBridge
Amazon EventBridge Scheduler now provides resource count metrics to help you monitor quota usage. These new metrics make it easier to track the number of schedules and schedule groups in your account and proactively manage service quotas.
Amazon DynamoDB
You can replicate Amazon DynamoDB table data across multiple AWS accounts and Regions. This enhances resiliency through account-level isolation, supports tailored security and data-perimeter controls. You can align workloads by business unit or environment and simplify governance requirements.
ECS also now supports Network Load Balancer (NLB) for linear and canary deployment strategies. This helps you perform gradual traffic shifting using NLBs, providing more flexibility in deployment pipelines for latency-sensitive applications.
Join our livestream every Tuesday at 11 AM PT for live discussions, Q&A sessions, and deep dives into serverless technologies. Watch episodes on-demand at serverlessland.com/office-hours.
The Serverless landing page has overall information about building serverless applications. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.
You can also follow the Developer Advocacy team to see the latest news, follow conversations, and interact with the team.
Generative AI brings promising innovation, transforming how individuals and organizations approach everything from customer service to content creation and more. As AI continues to expand its capabilities, organizations are increasingly focused on how they can integrate the responsible AI concepts into the development lifecycle of their AI applications.
Research from Accenture and Amazon Web Services (AWS) reveals compelling evidence for the business value of responsible AI practices, both internally within their organizations and externally to their users. Organizations that communicate a mature approach to responsible AI see an 82% improvement in employee trust in AI adoption, which directly leads to increased innovation. Additionally, companies that offer responsible AI-enabled products and services experience a 25% increase in customer loyalty and satisfaction.
Understanding the core dimensions of responsible AI
AWS identifies these key dimensions that form the backbone of responsible AI implementation:
Safety focuses on preventing harmful system output and misuse. This dimension focuses on steering AI systems to prioritize user and system safety.
Controllability focuses on mechanisms that monitor and steer AI system behavior. This dimension refers to the ability to manage, guide, and constrain AI systems to operate within specific parameters.
Fairness considers the impacts of AI on different groups of users.
Explainability focuses on understanding and evaluating system outputs.
Security and privacy focuses on making sure that data and models are appropriately obtained, used, and protected.
Veracity and robustness focuses on achieving correct system outputs, even with unexpected or adversarial inputs.
Governance makes sure that development, deployment, and management of AI systems align with ethical standards, legal requirements, and societal values.
Transparency focuses on understanding how AI systems make decisions, why the systems produce specific results, and what data the systems use.
When you implement AI systems, you should build safety into every phase of the AWS responsible AI lifecycle. The responsible AI lifecycle consists of the following three phases, each with distinct responsibility considerations for the safety dimension:
In the design and development phases, thoroughly evaluate potential safety risks. Understand what you want your AI application to do, what you don’t want it to do, and what you want to prevent it from doing. You should build safety guardrails into your systems from the beginning and make sure that your development teams understand the capabilities and limits of your AI application.
In the deployment phase, theory meets reality. During this phase, you should implement robust safety measures through multiple layers, from comprehensive user training to proactive monitoring and review processes. Every application, product, and feature must include clear safety protocols and user guidelines. You must think beyond the launch of an application and consider how to launch a holistic safety framework. This framework—which can contain steps such as red team testing—must protect your brand, users, and stakeholders.
Inthe operations phase, it’s important to maintain vigilance. Safety, like security, isn’t something you set up once and then ignore. Safety requires continuous monitoring and adaptation. To catch potential safety issues early, you can implement real-time feedback mechanisms to conduct regular performance evaluations. You can also continuously monitor for shifts in how your application is used, or functions that could compromise safety. Because safety considerations and risks evolve as technology evolves, it’s crucial to understand that adjustments are necessary over time.
Foundation models in Amazon Bedrock are inherently designed with safety mechanisms to prevent harmful outputs. However, you can implement additional input safety systems in production environments to provide critical early detection capabilities to identify problematic content, users, or patterns.
Note: Amazon Bedrock might implement automated abuse detection mechanisms to identify potential violations of the AWS Acceptable Use Policy (AUP) and Service Terms, including the Responsible AI Policy or a third-party model provider’s AUP.
To maintain trust in your AI services, preventative action is key, while also efficiently planning and managing development resources. Introduce observability and safety guardrails early in development to support long-term scalability and help identify potential issues before they affect your users. To begin this process, thoroughly scope your AI use case with the following actions:
Understand your users
Anticipate potential misuse scenarios
Define your risk tolerance
This scope guides your development of a precise safety framework that addresses the specific risks of your AI implementation while you maintain expected performance. For this scope, you can use AWS specialized tools designed specifically to monitor and protect Amazon Bedrock applications.
Using CloudWatch to monitor Amazon Bedrock
Amazon CloudWatch provides essential visibility into AI system behavior and performance. When you configure comprehensive logging, you can capture important information across user segments and interaction types, such as the following:
Request volumes
Response latencies
Rejection rates
Content filtering triggers
You can use this information to identify potential abuse patterns or unexpected behaviors before they affect operations. CloudWatch dashboards visualize metrics according to monitoring priorities, and automated alerts provide prompt notification when you exceed thresholds. This infrastructure transforms interaction data into actionable insights and supports continuous safety improvement.
Note: By default, Amazon Bedrock logging is turned off. You must turn on logging for your application. To configure this, contact your account manager.
Using Amazon Bedrock Guardrails to customize safeguards
Amazon Bedrock Guardrails offers configurable protection mechanisms tailored to specific risk profiles and content policies. You can customize Bedrock Guardrails to match your application requirements, such as:
Configure sensitive information detection and redaction parameters aligned with data policies
Additionally, you can configure controls that prioritize accuracy and prevent hallucinations while maintaining creative flexibility based on your application needs. When you thoughtfully configure Guardrails, you can balance performance and safety according to your specific use case requirements and risk factors.
The abuse response process
As AI safety evolves and new risks emerge, abuse might still occur even if you implement safety mechanisms. If you receive an abuse report from the AWS Trust & Safety team, then complete the following steps to help effectively address the issue:
Acknowledge receipt: Acknowledge the receipt of the abuse report within 24 hours. If your team is still conducting their investigation, then inform AWS that the investigation is ongoing. Provide the number of days expected to complete the investigation.
Investigate the issue: Thoroughly investigate the issue, including examining the logs (if enabled), reviewing Amazon Bedrock inputs, and checking for unauthorized access. While AWS abuse reports include a small sample of prompt IDs for you to investigate, investigate usage of your Amazon Bedrock application. Check for patterns to see if there’s a systemic issue that’s leading to abuse.
Take appropriate action: If appropriate, take action to implement fixes, update safeguards, address violating users, or redesign features. Consider if you need systemic or root-cause fixes, rather than addressing one abusive end user. An abuse incident by one user could indicate vulnerabilities in your safety mechanisms that can lead to continuous abuse.
Report back to AWS Trust & Safety: Following your investigation and implementation of fixes, provide an update to AWS Trust & Safety on your findings and remediation steps. Be transparent about what happened and how you addressed the issue. If you think that no violation occurred, then provide context on how you came to this conclusion. Include examples of the prompts and your business use case where possible.
Conclusion
To learn more about safety and responsible AI development, explore AWS resources, including the Responsible AI portal and machine learning best practices documentation. These resources provide additional tools and frameworks to build safe, effective AI systems that drive innovation and maintain safety standards.
Late March took me to Seattle for the Specialist Tech Conference, one of the most energizing gatherings of AWS specialists from around the world. It was an incredible opportunity to connect with peers, exchange experiences, and go deep on the latest advancements in Generative AI and Amazon Bedrock — and a powerful reminder of something I truly believe in: when specialists come together to challenge each other, explore edge cases, and co-create solutions, the impact goes far beyond the meeting room. In a fast-moving space like AI, having a strong internal community isn’t a nice-to-have — it’s a competitive advantage.
Now, let’s get into this week’s AWS news…
Headlines
Anthropic partnership: Claude on AWS Trainium and Graviton, and Claude Cowork in Amazon Bedrock – This week, AWS and Anthropic deepened their product collaboration in meaningful ways for builders. Anthropic is now training its most advanced foundation models on AWS Trainium and Graviton infrastructure, co-engineering directly at the silicon level with Annapurna Labs to maximize computational efficiency from the hardware up through the full stack.
Claude Cowork is now available in Amazon Bedrock — Claude Cowork brings Anthropic’s collaborative AI capabilities directly to enterprise builders within the AWS ecosystem, enabling teams to work alongside Claude as a true collaborator, not just a tool. You can now deploy Claude Cowork within your existing Amazon Bedrock environment, keeping your data secure within AWS while leveraging the full power of Claude for team-based AI workflows.
Claude Platform on AWS (Coming soon) — A unified developer experience to build, deploy, and scale Claude-powered applications without leaving AWS. If you’re building with Generative AI on AWS, this is a significant step forward in what you’ll be able to do with Claude directly through Amazon Bedrock.
Meta signs agreement with AWS to power agentic AI on Amazon’s Graviton chips — Meta has signed an agreement to deploy AWS Graviton processors at scale, starting with tens of millions of Graviton cores to power CPU-intensive agentic AI workloads — including real-time reasoning, code generation, search, and multi-step task orchestration.
Last week’s launches
Here are some launches and updates from this past week that caught my attention:
AWS Lambda functions can now mount Amazon S3 buckets as file systems with S3 Files — You can now mount Amazon S3 buckets as file systems in AWS Lambda using S3 Files, enabling your functions to perform standard file operations without downloading data for processing. Built on Amazon EFS, S3 Files provides the simplicity of a file system with the scalability, durability, and cost-effectiveness of S3 — and multiple Lambda functions can connect to the same file system simultaneously, sharing data through a common workspace. This is particularly valuable for AI and machine learning workloads where agents need to persist memory and share state across pipeline steps.
Amazon EKS Hybrid Nodes gateway for hybrid Kubernetes networking — Amazon Elastic Kubernetes Service now offers the Amazon EKS Hybrid Nodes gateway, which automates networking between your EKS cluster VPC and Kubernetes Pods running on EKS Hybrid Nodes. You can now eliminate the need to make on-premises pod networks routable or coordinate network infrastructure changes, greatly simplifying hybrid Kubernetes environments. The gateway automatically enables pod-to-pod traffic across cloud and on-premises environments, control plane-to-webhook communication, and connectivity for AWS services like Application Load Balancers, and is available at no additional charge.
Amazon Aurora Serverless: Up to 30% better performance, smarter scaling, and still scales to zero — Amazon Aurora Serverless just got faster and smarter, with up to 30% better performance than the previous version and an enhanced scaling algorithm designed to handle workloads where multiple tasks compete for resources — like busy APIs and agentic AI applications with bursts of activity and long idle windows. You can now run even more demanding workloads serverlessly, paying only for what you use, and automatically scaling to zero when not in use. All improvements are available in platform version 4 at no additional cost.
Amazon Bedrock AgentCore adds new features to help developers build agents faster — Amazon Bedrock AgentCore introduces a managed harness (preview), the AgentCore CLI, and AgentCore skills for coding assistants, helping developers go from idea to working agent prototype faster. The managed harness lets you define an agent by specifying a model, system prompt, and tools and run it immediately with no orchestration code required — and when you’re ready for full control, you can export the harness orchestration as Strands-based code. The AgentCore CLI deploys your agents with the governance and auditability of infrastructure-as-code (AWS CDK today, Terraform coming soon), and is available in 14 AWS Regions at no additional charge.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news
Here are some additional posts and resources that you might find interesting:
Introducing granular cost attribution for Amazon Bedrock — This post walks through how Amazon Bedrock’s granular cost attribution works and covers practical example cost tracking scenarios. You can now tag and track Bedrock usage costs at a finer level of detail — useful for organizations running multiple teams or projects on Bedrock who need precise cost visibility and chargeback capabilities.
Automating Incident Investigation with AWS DevOps Agent and Salesforce MCP Server — This post (co-written with Salesforce) shows how AWS DevOps Agent, integrated with the Salesforce MCP Server, automates the full lifecycle of infrastructure incident investigation — from identifying issues and diagnosing root causes to notifying customers through Salesforce Service Cloud. It’s a compelling real-world example of how AI agents and MCP-based tool connectivity are reshaping DevOps workflows in production, dramatically reducing mean time to resolution.
Microcredentials from AWS are now free — Here’s why that matters — You can now access AWS microcredentials at no cost through AWS Skill Builder in all countries where the platform is offered. Unlike traditional multiple-choice certifications, microcredentials are hands-on assessments that place builders in simulated business scenarios where they configure, troubleshoot, and optimize directly in a live AWS environment — the same way they would on the job. A great opportunity to validate real cloud skills without a cost barrier.
Amazon SageMaker AI now supports optimized generative AI inference recommendations — You can now use Amazon SageMaker AI to automatically identify optimized deployment configurations for your generative AI models, including instance type, container, and inference parameters. This new capability takes the guesswork out of tuning inference infrastructure, helping you reduce costs and improve latency for your AI applications in production.
Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:
What’s Next with AWS — Tune in on April 28 for What’s Next with AWS, a virtual event featuring the latest announcements and product updates directly from AWS teams. A great opportunity to get up to speed on what’s new before diving into the week’s launches.
AWS Summits — AWS Summits are free in-person events where you can explore the latest in cloud and AI innovation, learn best practices, and network with builders and experts. Coming up in May: Singapore (May 6), Tel Aviv (May 6), Warsaw (May 6), Stockholm (May 7), Sydney (May 13–14), Hamburg (May 20), Seoul (May 20), Amsterdam (May 27), Bangkok (May 28), Milan (May 28), and Mumbai (May 28). And in June, join us in Los Angeles (June 10). Check the full schedule and register at the link above.
AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Athens, Greece (April 28), Vancouver, Canada (May 1), İstanbul, Türkiye (May 9), and Panama City, Panama (May 23). If you’re in Latin America, mark your calendar for the AWS Community Day Belo Horizonte (August 22) — registration is open at awscommunityday.com.br.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
— Daniel Abib
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
Last week I had the honor of delivering a commencement speech at the University of Namur (uNamur) for their 2025 graduation ceremony.
Standing in front of freshly minted computer science graduates, I talked about the future of software development in the age of AI. My message to them was simple: AI will not make you obsolete. We’ve seen tools evolve over the decades, from punch cards to IDEs to AI-assisted coding, but the work remains yours, not the tool’s. The developers who will thrive are those who stay curious, think in systems, communicate with precision, and take ownership of what they build. The world needs more people with coding skills, not fewer. AI raises the bar on what we can accomplish, and that’s a good thing.
Now, let’s get into this week’s AWS news.
Headlines Anthropic’s Claude Opus 4.7 is now available in Amazon Bedrock – Anthropic’s most intelligent Opus model is now available in Amazon Bedrock, with improved performance across coding, long-running agents, and professional knowledge work. Claude Opus 4.7 scores 64.3% on SWE-bench Pro and 87.6% on SWE-bench Verified, extending its lead in agentic coding with stronger long-horizon autonomy and complex code reasoning. It also does better on knowledge work tasks like document creation, financial analysis, and multi-step research.
The model runs on Bedrock’s next-generation inference engine with dynamic capacity allocation, adaptive thinking (letting Claude allocate thinking token budgets based on request complexity), and the full 1M token context window. It also adds high-resolution image support for better accuracy on charts, dense documents, and screen UIs. Claude Opus 4.7 is available at launch in US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm), with up to 10,000 requests per minute per account per Region.
AWS Interconnect is now generally available with a new option to simplify last-mile connectivity – AWS Interconnect brings two managed private connectivity capabilities to general availability. The first, AWS Interconnect – Multicloud, provides Layer 3 private connections between AWS VPCs and other cloud providers (Google Cloud available now, Azure and OCI coming later in 2026). Traffic flows over the AWS global backbone and the partner cloud’s private network, never over the public internet, with built-in MACsec encryption, multi-facility resiliency, and CloudWatch monitoring. AWS published the underlying specification on GitHub under Apache 2.0 so any cloud provider can become an Interconnect partner.
The second capability, AWS Interconnect – Last Mile, simplifies high-speed private connections from branch offices, data centers, and remote locations to AWS through existing network providers. It provisions 4 redundant connections across 2 physical locations automatically, configures BGP routing, activates MACsec encryption and Jumbo Frames by default, and offers bandwidth from 1 Gbps to 100 Gbps adjustable from the console without reprovisioning. Last Mile launches in US East (N. Virginia) with Lumen as the initial partner.
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Amazon ECR pull through cache now supports referrer discovery and sync — ECR’s pull through cache now automatically discovers and syncs OCI referrers (image signatures, SBOMs, attestations) from upstream registries into your private repositories. This means end-to-end image signature verification and SBOM discovery workflows work without client-side workarounds.
AWS Transform is now available in Kiro and VS Code — AWS Transform, the agentic migration and modernization factory, is now accessible via Kiro (as a Power) and VS Code (as an extension). You can run custom transformations for common patterns like Java/Python/Node.js version upgrades and AWS SDK migrations directly from your IDE, with job state shared across the web console, CLI, and IDE.
Aurora DSQL launches connector for PHP — A new Aurora DSQL Connector for PHP (PDO_PGSQL) simplifies building PHP applications on Aurora DSQL by automatically generating IAM tokens, handling SSL configuration, managing connection pooling, and providing opt-in optimistic concurrency control retry with exponential backoff.
Amazon Q supports document-level access controls for Google Drive — Amazon Q now enforces document-level access controls for Google Drive knowledge bases, combining indexed ACL replication for fast pre-retrieval filtering with real-time permission checks against Google Drive at query time.
AWS Secrets Manager now supports hybrid post-quantum TLS — Secrets Manager now supports hybrid post-quantum key exchange using ML-KEM to protect secrets against both current and future quantum computing threats. This is automatically enabled in Secrets Manager Agent 2.0.0+, Lambda Extension v19+, and the CSI Driver 2.0.0+.
Amazon EC2 C8in and C8ib instances are now generally available — Powered by custom 6th-gen Intel Xeon Scalable processors and 6th-gen AWS Nitro cards, these instances deliver up to 43% higher performance over C6in. C8in offers 600 Gbps network bandwidth (highest among enhanced networking EC2 instances), while C8ib delivers up to 300 Gbps EBS bandwidth (highest among non-accelerated compute instances), scaling up to 384 vCPUs.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts and resources that you might find interesting:
Navigating enterprise networking challenges with Amazon EKS Auto Mode — This post explains how EKS Auto Mode automates Kubernetes networking infrastructure including VPC CNI configuration, load balancer provisioning, and DNS management, reducing operational overhead while preserving enterprise security controls.
Introducing granular cost attribution for Amazon Bedrock — My colleague Micah talked about this feature last week already, but the blog post came out after last week’s roundup. Amazon Bedrock now automatically attributes inference costs to the specific IAM principal that made each API call, with results flowing into AWS Cost and Usage Reports (CUR 2.0). You can aggregate costs by team, project, or cost center using IAM principal tags and session tags.
Accelerate development workflows with Amazon EBS Volume Clones — EBS Volume Clones let you create instant, point-in-time copies of EBS volumes that are immediately usable without waiting for data transfer. The post highlights use cases including dev/test environment refreshes, disaster recovery testing, and CI/CD pipeline acceleration.
Modernize VB6 applications at scale with AWS Transform Custom — A walkthrough of using AWS Transform Custom’s agentic AI capabilities to convert legacy Visual Basic 6.0 applications to modern C# ASP.NET Core web applications, addressing challenges like COM dependencies, ADO-to-Entity Framework migration, and VB6 forms-to-Blazor UI conversion.
Today, we’re announcing Claude Opus 4.7 in Amazon Bedrock, Anthropic’s most intelligent Opus model for advancing performance across coding, long-running agents, and professional work.
Claude Opus 4.7 is powered by Amazon Bedrock’s next generation inference engine, delivering enterprise-grade infrastructure for production workloads. Bedrock’s new inference engine has brand-new scheduling and scaling logic which dynamically allocates capacity to requests, improving availability particularly for steady-state workloads while making room for rapidly scaling services. It provides zero operator access—meaning customer prompts and responses are never visible to Anthropic or AWS operators—keeping sensitive data private.
According to Anthropic, Claude Opus 4.7 model provides improvements across the workflows that teams run in production such as agentic coding, knowledge work, visual understanding,long-running tasks. Opus 4.7 works better through ambiguity, is more thorough in its problem solving, and follows instructions more precisely.
Agentic coding: The model extends Opus 4.6’s lead in agentic coding, with stronger performance on long-horizon autonomy, systems engineering, and complex code reasoning tasks. According to Anthropic, the model records high-performance scores with 64.3% on SWE-bench Pro, 87.6% on SWE-bench Verified, and 69.4% on Terminal-Bench 2.0.
Knowledge work: The model advances professional knowledge work, with stronger performance on document creation, financial analysis, and multi-step research workflows. The model reasons through underspecified requests, making sensible assumptions and stating them clearly, and self-verifies its output to improve quality on the first step. According to Anthropic, the model reaches 64.4% on Finance Agent v1.1.
Long-running tasks: The model stays on track over longer horizons, with stronger performance over its full 1M token context window as it reasons through ambiguity and self-verifies its output.
Vision: the model adds high-resolution image support, improving accuracy on charts, dense documents, and screen UIs where fine detail matters.
The model is an upgrade from Opus 4.6 but may require prompting changes and harness tweaks to get the most out of the model. To learn more, visit Anthropic’s prompting guide.
Claude Opus 4.7 model in action You can get started with Claude Opus 4.7 model in Amazon Bedrock console. Choose Playground under Test menu and choose Claude Opus 4.7 when you select model. Now, you can test your complex coding prompt with the model.
I run the following prompt example about technical architecture decision: Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions.
To get started with making your first API call to Amazon Bedrock in minutes, choose Quickstart in the left navigation pane in the console. After choosing your use case, you can generate a short term API key to authenticate your requests as testing purpose.
When you choose the API method such as the OpenAI-compatible Responses API, you can get sample codes to run your prompt to make your inference request using the model.
To invoke the model through the Anthropic Claude Messages API, you can proceed as follows using anthropic[bedrock] SDK package for a streamlined experience:
from anthropic import AnthropicBedrockMantle
# Initialize the Bedrock Mantle client (uses SigV4 auth automatically)
mantle_client = AnthropicBedrockMantle(aws_region=REGION)
# Create a message using the Messages API
message = mantle_client.messages.create(
    model="anthropic.claude-opus-4-7",
    max_tokens=2048,
    messages=[
	    {"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions"}
    ]
)
print(message.content[0].text)
You can also run the following command to invoke the model directly to bedrock-runtime endpoint using the AWS CLI and the Invoke API:
aws bedrock-runtime invoke-model \
 --model-id anthropic.claude-opus-4-7 \
 --region us-east-1 \
 --body '{"messages": [{"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."}], "max_tokens": 512, "temperature": 0.5, "top_p": 0.9}' \
 --cli-binary-format raw-in-base64-out \
invoke-model-output.txt
For more intelligent reasoning capability, you can use Adaptive thinking with Claude Opus 4.7, which lets Claude dynamically allocate thinking token budgets based on the complexity of each request.
Things to know Let me share some important technical details that I think you’ll find useful.
Choosing APIs: You can choose from a variety of Bedrock APIs for model inference, as well as the Anthropic Messages API. The Bedrock-native Converse API supports multi-turn conversations and Guardrails integration. The Invoke API provides direct model invocation and lowest-level control.
Scaling and capacity: Bedrock’s new inference engine is designed to rapidly provision and serve capacity across many different models. When accepting requests, we prioritize keeping steady state workloads running, and ramp usage and capacity rapidly in response to changes in demand. During periods of high demand, requests are queued, rather than rejected. Up to 10,000 requests per minute (RPM) per account per Region are available immediately, with more available upon request.
Now available Anthropic’s Claude Opus 4.7 model is available today in the US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm) Regions; check the full list of Regions for future updates. To learn more, visit the Claude by Anthropic in Amazon Bedrock page and the Amazon Bedrock pricing page.
In my last Week in Review post, I mentioned how much time I’ve been spending on AI-Driven Development Lifecycle (AI-DLC) workshops with customers this year. A common theme in those sessions is the need for better cost visibility. Teams are moving fast with AI, but as they go from experimenting to full production, finance and leadership really need to know who is using which resources and at what cost. That’s why I was so excited to see the launch of Amazon Bedrock new support for cost allocation by IAM user and role this week. This lets you tag IAM principals with attributes like team or cost center and then activate those tags in your Billing and Cost Management console. The resulting cost data flows into AWS Cost Explorer and the detailed Cost and Usage Report, giving you a clear line of sight into model inference spending. Whether you’re scaling agents across teams, tracking foundation model use by department, or running tools like Claude Code on Amazon Bedrock, this new feature is a game changer for tracking and managing your AI investments. You can get all the details on setting this up in the IAM principal cost allocation documentation.
Now, let’s get into this week’s AWS news…
Headlines Amazon Bedrock now offers Claude Mythos Preview Anthropic’s most sophisticated AI model to date is now available on Amazon Bedrock as a gated research preview through Project Glasswing. Claude Mythos introduces a new model class focused on cybersecurity, capable of identifying sophisticated security vulnerabilities in software, analyzing large codebases, and delivering state of the art performance across cybersecurity, coding, and complex reasoning tasks. Security teams can use it to discover and address vulnerabilities in critical software before threats emerge. Access is currently limited to allowlisted organizations, with Anthropic and AWS prioritizing internet critical companies and open source maintainers.
AWS Agent Registry for centralized agent discovery and governance now in preview AWS launched Agent Registry through Amazon Bedrock AgentCore, providing organizations with a private catalog for discovering and managing AI agents, tools, skills, MCP servers, and custom resources. The registry helps teams locate existing capabilities rather than duplicating them, with semantic and keyword search, approval workflows, and CloudTrail audit trails. It is accessible via the AgentCore Console, AWS CLI, SDK, and as an MCP server queryable from IDEs.
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Announcing Amazon S3 Files, making S3 buckets accessible as file systems — Amazon S3 Files transforms S3 buckets into shared file systems that connect any AWS compute resource directly with your S3 data. Built on Amazon EFS technology, it delivers full file system semantics with low latency performance, caching actively used data and providing multiple terabytes per second of aggregate read throughput. Applications can access S3 data through both file system and S3 APIs simultaneously without code modifications or data migration.
Amazon OpenSearch Service supports Managed Prometheus and agent tracing —Amazon OpenSearch Service now provides a unified observability platform that consolidates metrics, logs, traces, and AI agent tracing into a single interface. The update includes native Prometheus integration with direct PromQL query support, RED metrics monitoring, and OpenTelemetry GenAI semantic convention support for LLM execution visibility. Operations teams can correlate slow traces to logs and overlay Prometheus metrics on dashboards without switching between tools.
Amazon WorkSpaces Advisor now available for AI powered troubleshooting— AWS launched Amazon WorkSpaces Advisor, an AI powered administrative tool that uses generative AI to help IT administrators troubleshoot Amazon WorkSpaces Personal deployments. It analyzes WorkSpace configurations, detects problems automatically, and provides actionable recommendations to restore service and optimize performance.
Amazon Braket adds support for Rigetti’s 108 qubit Cepheus QPU — Amazon Braket now offers access to Rigetti’s Cepheus-1-108Q device, the first 100+ qubit superconducting quantum processor on the platform. The modular design features twelve 9 qubit chiplets with CZ gates that offer enhanced resilience to phase errors. It supports multiple frameworks including Braket SDK, Qiskit, CUDA-Q, and Pennylane, with pulse level control for researchers.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts and resources that you might find interesting:
Understanding Amazon Bedrock model lifecycle — Machine learning blog post that walks through the stages foundation models go through in Bedrock from availability through deprecation, helping teams plan for model updates and manage version dependencies in production.
Deploy OpenClaw on AWS: Choose the right options for your AI workload — Builder Center guide comparing four AWS deployment options for OpenClaw: Amazon Lightsail for individual developers, Amazon EC2 for startups needing deeper AWS integration, Amazon Bedrock AgentCore for serverless multiuser scenarios, and Amazon EKS for enterprises requiring VM level isolation and advanced orchestration.
We’re bringing back the Kiro startup credits program — Kiro is relaunching its startup credits initiative, offering eligible early stage companies complimentary access to Kiro Pro+ for up to one year. The three tier program (Starter, Growth, Scale) provides 2 to 30 users based on team size, with rolling applications accepted globally.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
What’s Next with AWS(April 28, Virtual) Join this livestream at 9am PT for a candid discussion about how agentic AI is transforming how businesses operate. Featuring AWS CEO Matt Garman, SVP Colleen Aubrey, and OpenAI leaders discussing emerging agent capabilities, Amazon’s internal experiences, and new agentic solutions and platform capabilities.
At AWS, we’ve spent decades developing processes and tools that enable us to defend millions of customers simultaneously, wherever they operate around the world. Every day, our security and threat intelligence teams are doing work with AI and automation that most people never see. Our AI-powered log analysis system has reduced the time SecOps engineers spend analyzing security logs from an average of six hours to just seven minutes, a 50x productivity increase that lets us detect and respond to threats faster than ever. Across AWS, we analyze over 400 trillion network flows per day to detect patterns that signal emerging threats. In 2025 alone, we blocked over 300 million attempts to maliciously encrypt customer files hosted on Amazon S3.
What we learn protecting one customer helps protect all customers. At this scale, every threat we see makes our defenses stronger for everyone, and AI is already central to how we do it.
A new class of AI for cybersecurity
Today, Anthropic announced Project Glasswing, a cybersecurity initiative designed to secure the world’s most critical software and advance the cybersecurity practices the industry will need as AI grows more capable. Organizations that build or maintain critical digital infrastructure are getting early access to Claude Mythos Preview, a new class of AI model, to find and patch vulnerabilities in the systems the world depends on. Given our role in securing some of the world’s most essential infrastructure, AWS is playing an integral part in advancing this work.
Powering the project is Claude Mythos Preview, Anthropic’s most advanced AI model to date and a step-change in reasoning and AI capabilities for cybersecurity. Claude Mythos Preview represents a fundamentally new model class: more intelligent and capable than Anthropic’s previous frontier models, with higher performance on cybersecurity, software coding, and complex reasoning tasks.
As part of Project Glasswing, we’ve already applied Claude Mythos Preview to critical AWS codebases that undergo continuous AI-powered security reviews, and even in those well-tested environments, it’s helped us identify additional opportunities to strengthen our code. In our internal testing, Claude Mythos Preview has proven more productive than previous models at surfacing security findings, requiring less manual guidance from our engineers to deliver actionable results. We’ve also given early access to a select group of AWS customers, who are deploying Claude Mythos Preview in their own security workflows and helping shape how the model evolves. For us, Claude Mythos Preview is a natural extension of the AI tools we already use, and as the technology grows more powerful, so must our defenses.
This is exactly the kind of innovation that drives our work, and we’ve been working closely with Anthropic to help ensure Claude Mythos Preview is ready for enterprise use. AWS is Anthropic’s primary cloud provider for mission-critical workloads, safety research, and foundation model development. More broadly, AWS provides the foundational infrastructure that the world’s leading AI companies rely on to build, train, and deploy their most advanced models. We’re bringing decades of security experience to this partnership, helping to ensure Claude Mythos Preview is ready for even more organizations to build upon and operate securely at scale.
Claude Mythos Preview signals an upcoming wave of models that can find vulnerabilities and build working exploits at a scale and speed we haven’t seen before. Anthropic and AWS are taking a deliberately cautious approach to release. Access begins with a small number of organizations, prioritizing internet-critical companies and open-source maintainers whose software and digital services impact hundreds of millions of users. The goal: find and fix vulnerabilities in the world’s most critical software. Claude Mythos Preview is available in gated research preview through Amazon Bedrock with enterprise-grade security controls, including customer-managed encryption, VPC isolation, and detailed logging, so your team can explore Claude Mythos Preview’s capabilities without exposing production assets to unnecessary risk.
AWS architects services with security at the core
Our work with Project Glasswing is grounded in a philosophy we’ve developed over two decades of securing mission-critical workloads: you can’t wait for threats to materialize before building your defenses. You have to look around corners, adopt new technologies, build protections first, deploy them in your own operations at scale, and refine them based on what you learn.
That’s exactly what we’ve done at AWS with AI and security. Our approach spans the full spectrum: proactive defense through threat hunting and vulnerability research, dynamic response to active campaigns, and third-party certifications that verify our security practices meet the highest industry standards. This operational experience has taught us where AI accelerates security work and where human judgment remains essential. And it’s reinforced that security innovation must be pragmatic: proven in production before we ask you to rely on it.
That’s also why we help define what secure AI looks like. We became the first major cloud provider to achieve ISO 42001 certification for AI services. We’re active participants in OWASP, the Coalition for Secure AI, and the Frontier Model Safety Framework. And we co-founded the Open Cybersecurity Schema Framework (OCSF) to enable better threat intelligence sharing across the ecosystem. The AWS Nitro System provides mathematical isolation for workloads. Our zero-operator access architecture means AWS personnel can’t access your data. These aren’t aspirational goals. They’re how we operate today, at scale, every day.
Amazon Bedrock is where these principles come to life for AI. It provides policy-enforced access controls, built-in evaluation tools to measure how effectively models identify and validate vulnerabilities, and the ability to run workloads inside your own virtual private cloud. AWS is also the first cloud provider to achieve FedRAMP High and Department of Defense Security Requirements Guide Impact Level 4 and 5 authorizations for generally available Claude foundation models, reinforcing that Amazon Bedrock is where the most security-sensitive organizations already trust Anthropic’s technology.
How to get started today
The same principles that guide our work at AWS scale apply regardless of which AI tools you’re using: comprehensive observability, defense in depth, automation where it adds value, and human judgment where it’s essential. Here’s how to put them into practice.
Prepare for the next generation of AI security. Claude Mythos Preview signals an upcoming wave of AI models that will transform cybersecurity. Start strengthening your security posture now so your organization is ready as these capabilities become more broadly available. Claude Mythos Preview is available in gated preview through Amazon Bedrock, and access is limited to an initial allow-list of organizations. If your organization has been allow-listed, your AWS account team will reach out directly.
Run on-demand penetration testing with AWS Security Agent. Now generally available,AWS Security Agent delivers autonomous penetration testing that operates 24/7 at a fraction of the cost of manual penetration tests. It transforms penetration testing from a periodic bottleneck into an on-demand capability that scales with your development velocity across AWS, Azure, GCP, other cloud providers, and on-premises. AWS Security Agent represents a new class of frontier agents: autonomous systems that work independently to achieve goals, scale to tackle concurrent tasks, and run persistently without constant human oversight. It deploys specialized AI agents to discover, validate, and report security vulnerabilities through sophisticated multi-step attack scenarios. Unlike traditional scanners that generate findings without validation, AWS Security Agent identifies potential vulnerabilities, then attempts to exploit them with targeted payloads and attack chains to confirm they are legitimate security risks. Each finding includes CVSS risk scores, application-specific severity ratings, detailed reproduction steps, and remediation suggestions. The result: penetration testing that once took weeks now completes in hours, and security coverage that scales across your entire application portfolio, not just your most critical systems. New customers can explore AWS Security Agent with a 2-month free trial.
Build AI applications you can trust with Amazon Bedrock. For teams building with generative AI, the challenge isn’t just making AI work, it’s making AI work safely. Amazon Bedrock provides the security and safety controls you need to deploy AI responsibly. Its Automated Reasoning capability is the first and only AI safeguard to use formal logic to help prevent factual errors from hallucinations, providing verifiable explanations with 99% accuracy, a capability we’ve refined over more than a decade of applying formal methods across AWS storage, identity, and networking. Amazon Bedrock also provides customizable guardrails that block harmful content and enforce your content policies, along with comprehensive observability to track AI behavior and detect anomalies across your workloads.
The threat landscape isn’t waiting
The threat landscape isn’t waiting for us to catch up. Nation-state actors, ransomware operators, and supply chain attackers are already using AI to scale their operations. Our job is to stay ahead by building defenses first, deploying them at scale, and sharing what we learn so the entire community benefits.
That’s what we do every day at AWS. We prove technology works in our own operations before we ask customers to rely on it. We set standards rather than follow them. And we look around corners to address tomorrow’s challenges today.
As AI capabilities continue to evolve, this approach won’t change. We’ll keep building defenses first, refining them at scale, and working with partners like Anthropic to ensure the next generation of AI security tools meets the real-world needs of enterprises defending at this scale.
Last week, I visited AWS Hong Kong User Group with my team. Hong Kong has a small but strong community, and their energy and passion are high. They recently started a new AI user group, and we hope more people will join. I was able to strengthen my bond with the community through great food and conversation.
This week, I”ll first take a closer look at some of the key launches.
AWS DevOps Agent helps you run cloud operations—investigating incidents, reducing time to resolution, and preventing issues before they happen. Customers like United Airlines, Western Governors University, and T-Mobile are already using DevOps Agent to accelerate incident response and simplify operations at scale. At WGU, resolution time dropped from hours to minutes, and in preview customers report up to 75% lower MTTR and 3 to 5 times faster resolution. Learn more in Sébastien’s preview blog post and GA announcement.
AWS Security Agent brings continuous, context-aware penetration testing into the development lifecycle. This agent operates like a human penetration tester. Customers including LG CNS, HENNGE, and Wayspring are seeing strong results. At LG CNS, teams estimate over 50% faster testing and ~30% lower costs, along with significantly fewer false positives. Learn more in Esra’s preview blog post and GA announcement.
Both are designed to work across AWS cloud, multicloud, and on-prem environments. You can have an always-available teammate that can handle the heavy lifting, so you can focus on what matters most.
AWS Service Availability Updates When the availability of an AWS service or feature changes, we provide customers guidance in AWS Product Lifecycle Changes on available alternatives and support for migration so that disruptions to your operations are minimized. The following lifecycle changes were updated on March 31, 2026.
Availability change guide for services in maintenance
We understand that changes in availability can impact your operations. For specific guidance, consult the relevant service documentation or contact AWS Support.
Last week’s launches Here are last week’s launches that caught my attention:
Today, we’re announcing the general availability of cross-account safeguards in Amazon Bedrock Guardrails, a new capability that enables centralized enforcement and management of safety controls across multiple AWS accounts within an organization.
With this new capability, you can specify a guardrail in a new Amazon Bedrock policy within the management account of your organization that automatically enforces configured safeguards across all member entities for every model invocation with Amazon Bedrock. This organization-wide implementation supports uniform protection across all accounts and generative AI applications with centralized control and management. This capability also offers flexibility to apply account-level and application-specific controls depending on use case requirements in addition to organizational safeguards.
Organization-level enforcements apply a single guardrail from your organization’s management account to all entities within the organization through policy settings. This guardrail automatically enforces filters across all member entities, including organizational units (OUs) and individual accounts, for all Amazon Bedrock model invocations.
Account-level enforcement enables automatic enforcement of configured safeguards across all Amazon Bedrock model invocations in your AWS account. The configured safeguards in the account-level guardrail apply to all inference API calls.
You can now establish and centrally manage dependable, comprehensive protection through a single, unified approach. This supports consistent adherence to corporate responsible AI requirements while significantly reducing the administrative burden of monitoring individual accounts and applications. Your security team no longer needs to oversee and verify configurations or compliance for each account independently.
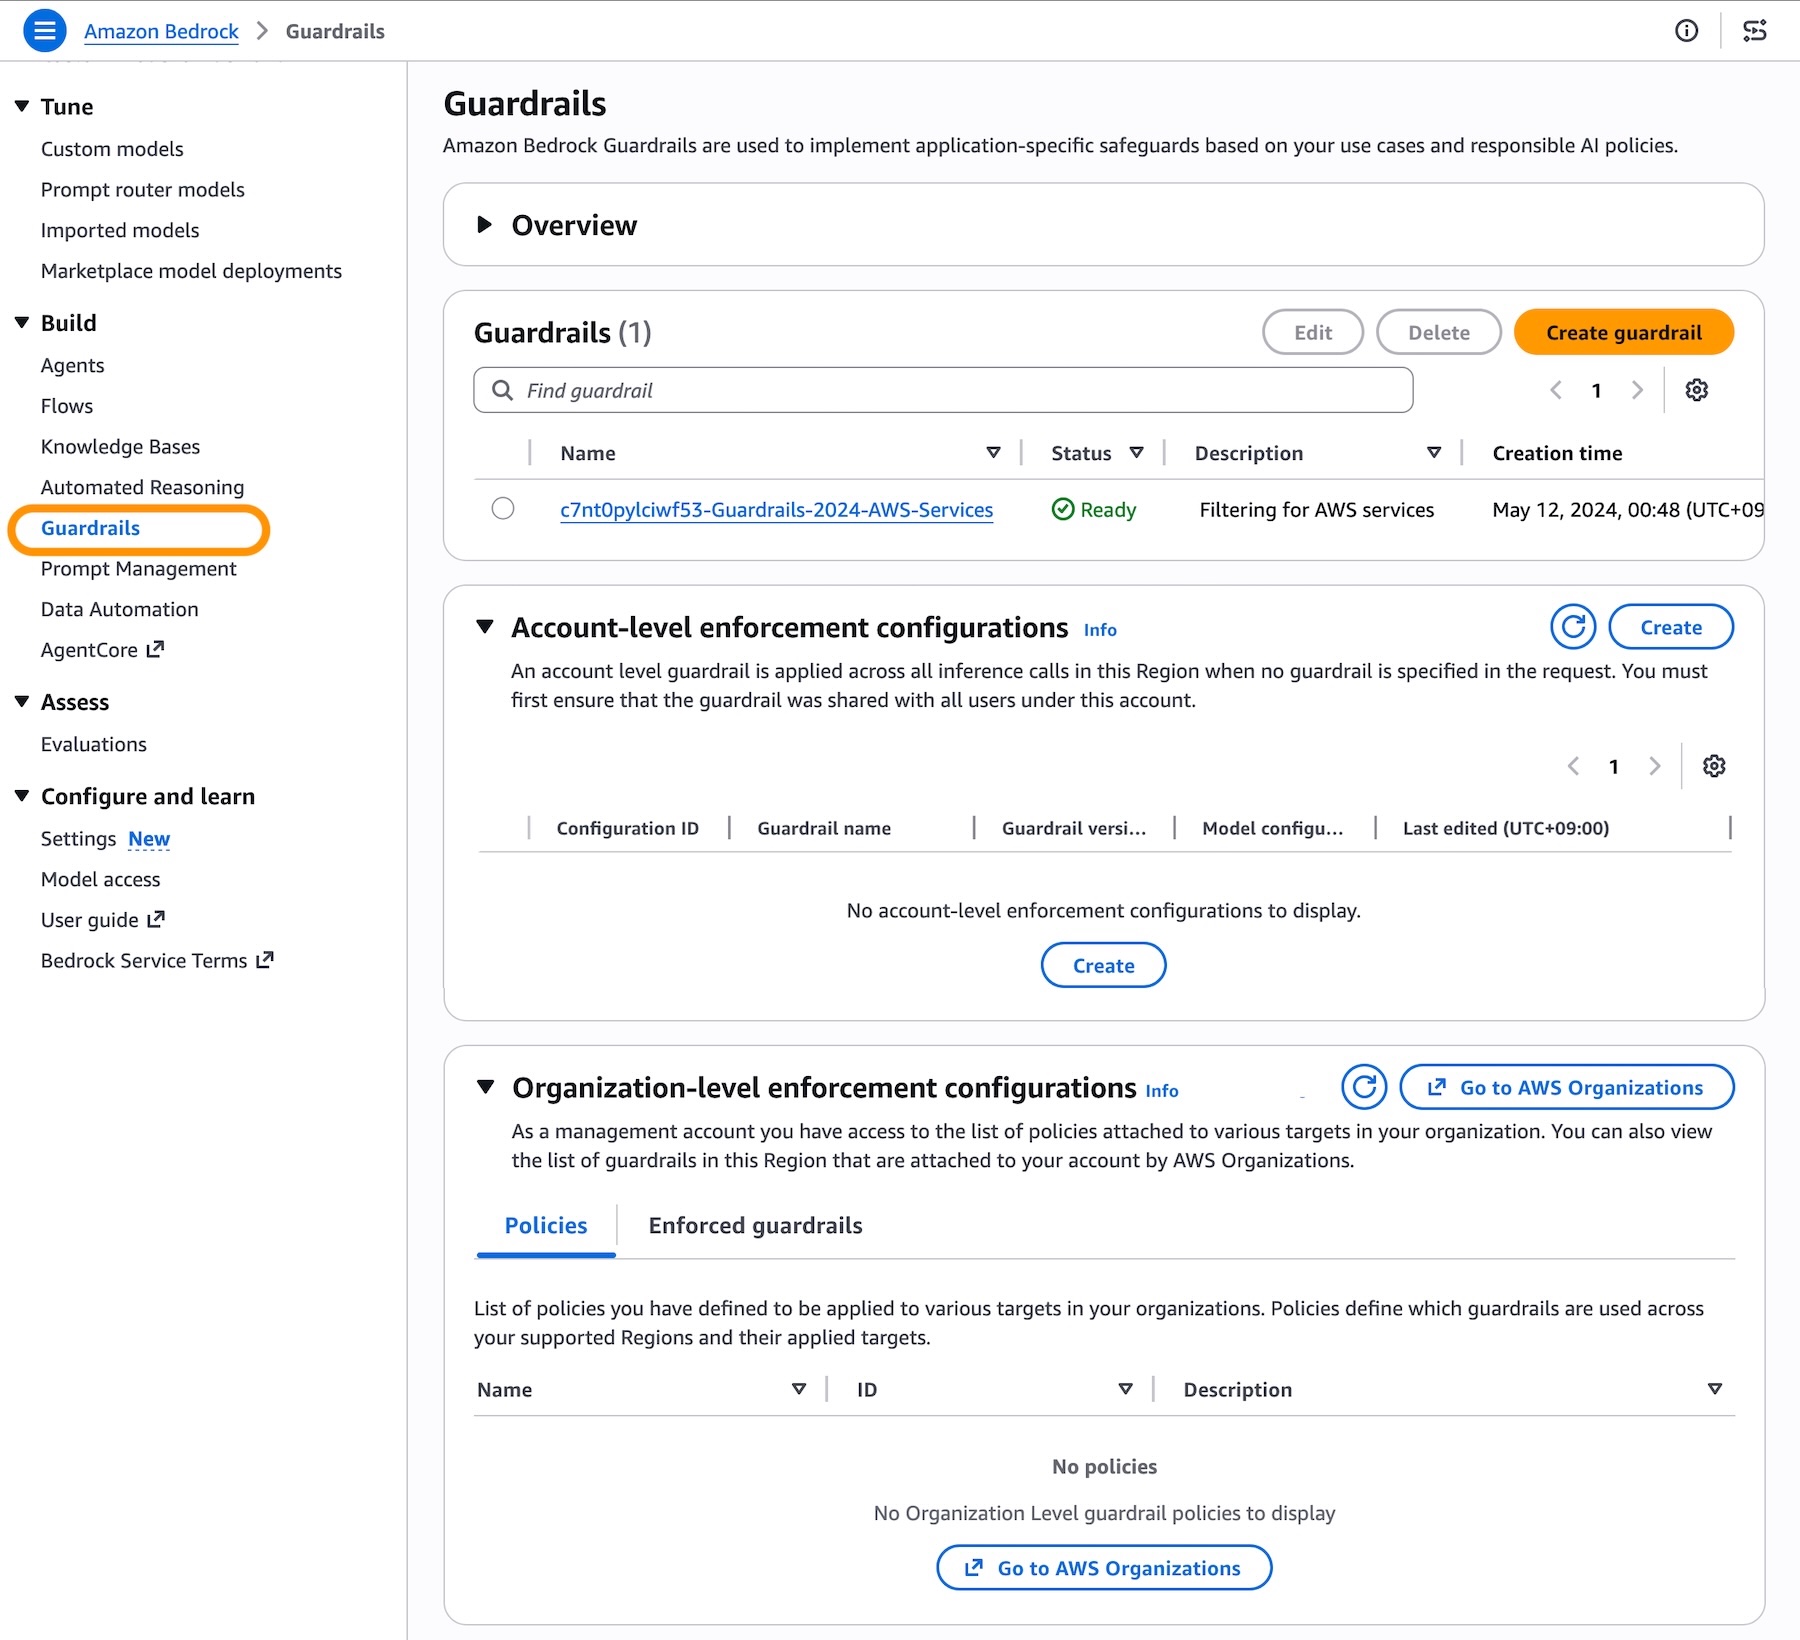
Getting started with centralized enforcement in Amazon Bedrock Guardrails You can get started with account-level and organization-level enforcement configuration in the Amazon Bedrock Guardrails console. Before the enforcement configuration, you need to create a guardrail with a particular version to support the guardrail configuration remains immutable and cannot be modified by member accounts and complete prerequisites for using the new capability such as resource-based policies for guardrails.
To enable account-level enforcement, choose Create in the section of Account-level enforcement configurations.
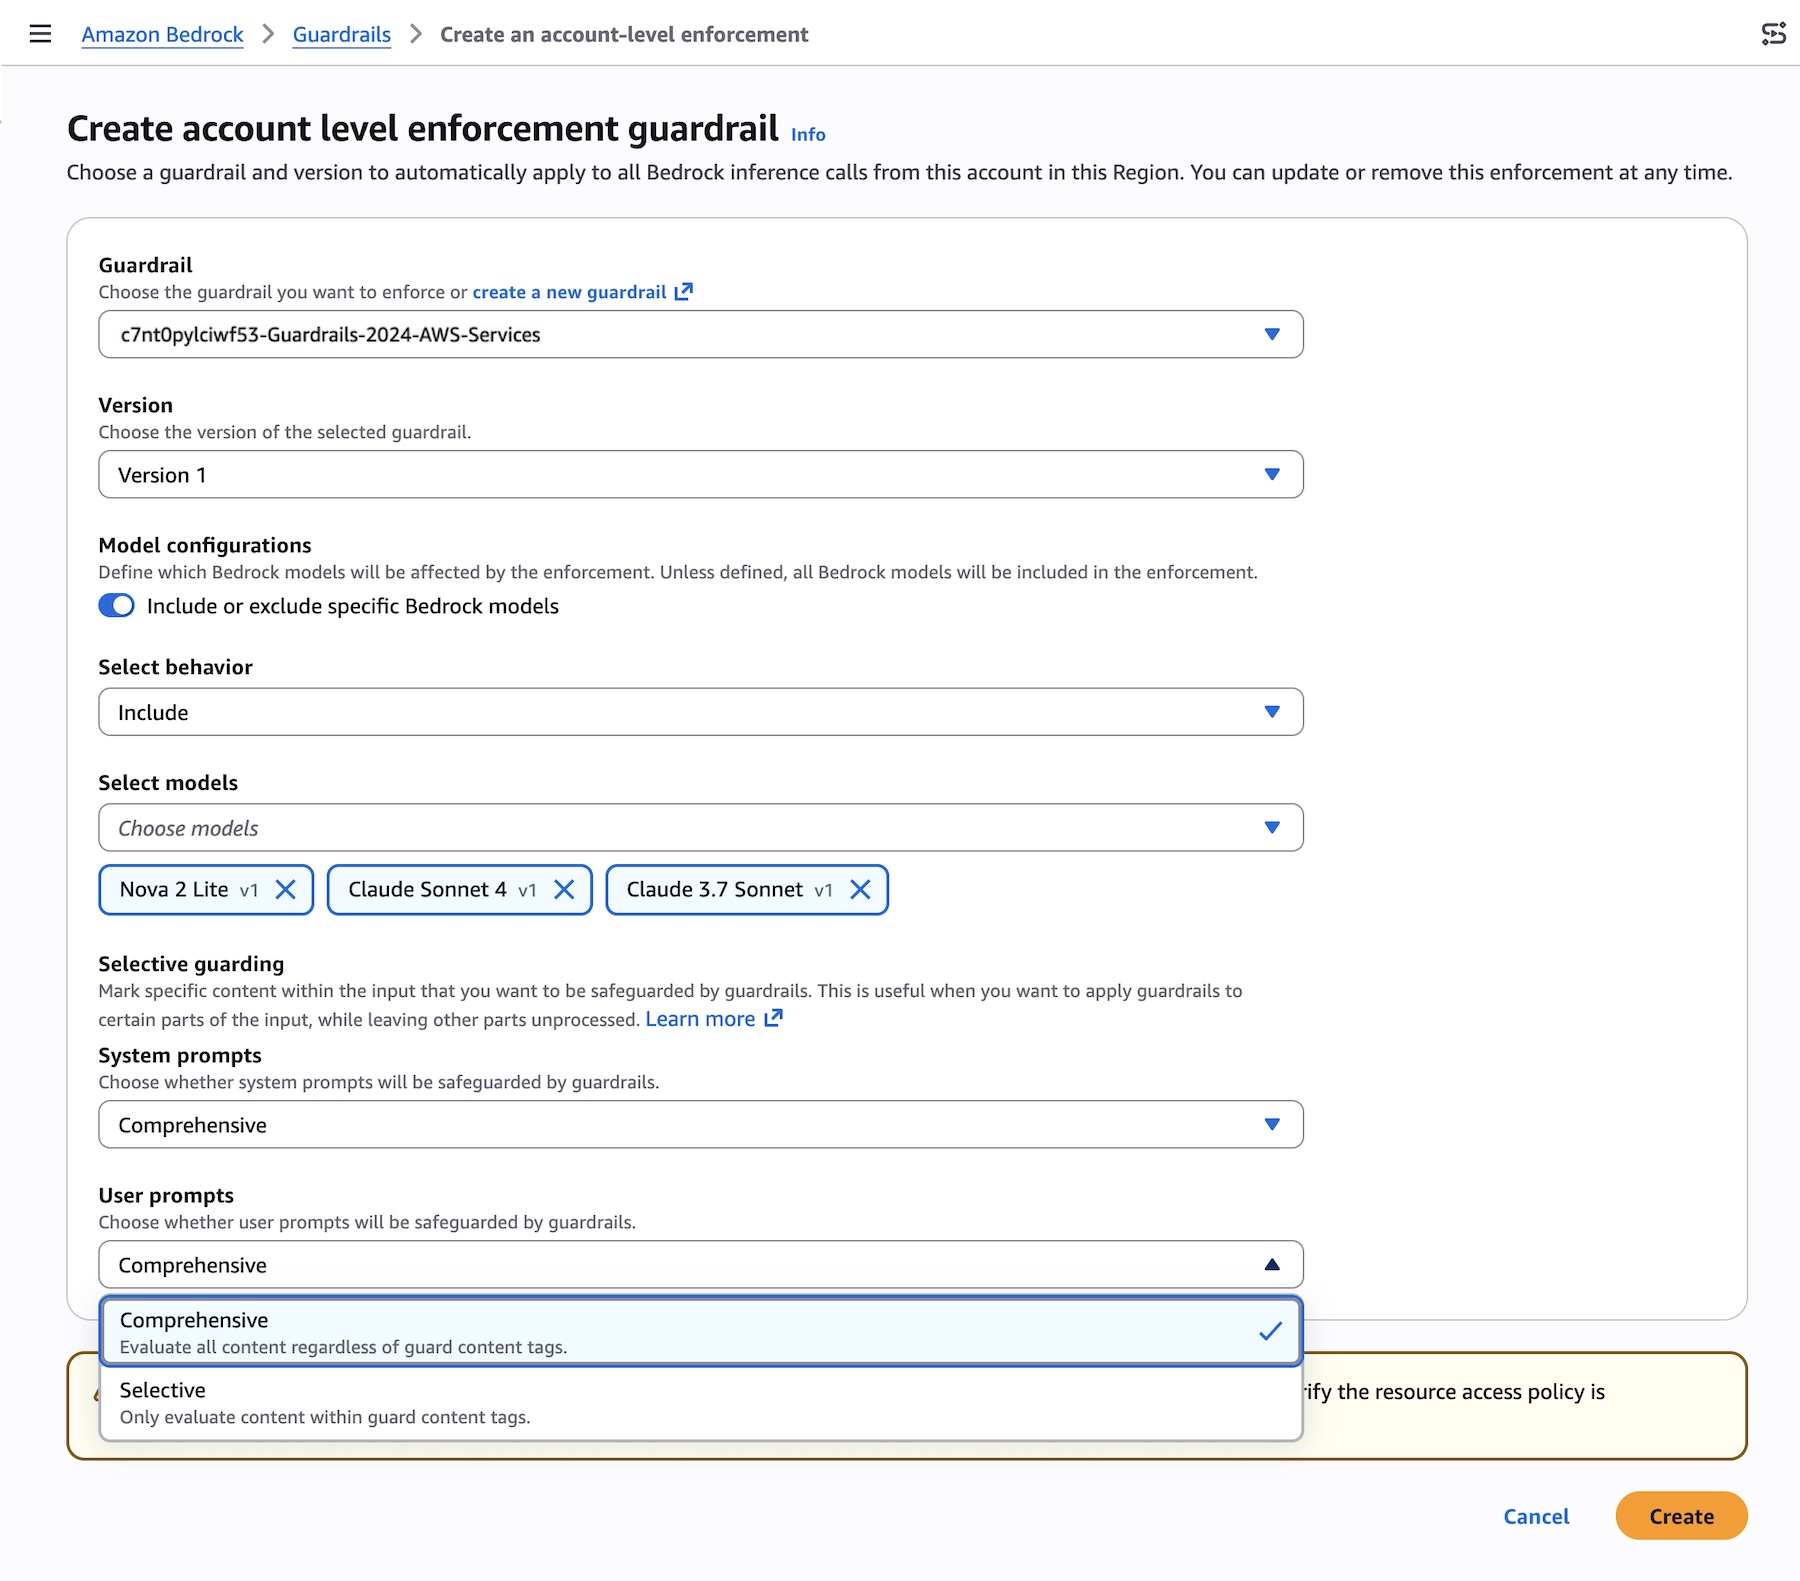
You can choose the guardrail and version to automatically apply to all Bedrock inference calls from this account in this Region. With general availability, we introduce the new feature defining which models will be affected by the enforcement with either Include or Exclude behavior.
You can also configure selective content guarding controls for system prompts and user prompts with either Comprehensive or Selective.
Use Comprehensive when you want to enforce guardrails on everything, regardless of what the caller tags. This is the safer default when you don’t want to rely on callers to correctly identify sensitive content.
Use Selective when you trust callers to tag the right content and want to reduce unnecessary guardrail processing. This is useful when callers handle a mix of pre-validated and user-generated content, and only need guardrails applied to specific portions.
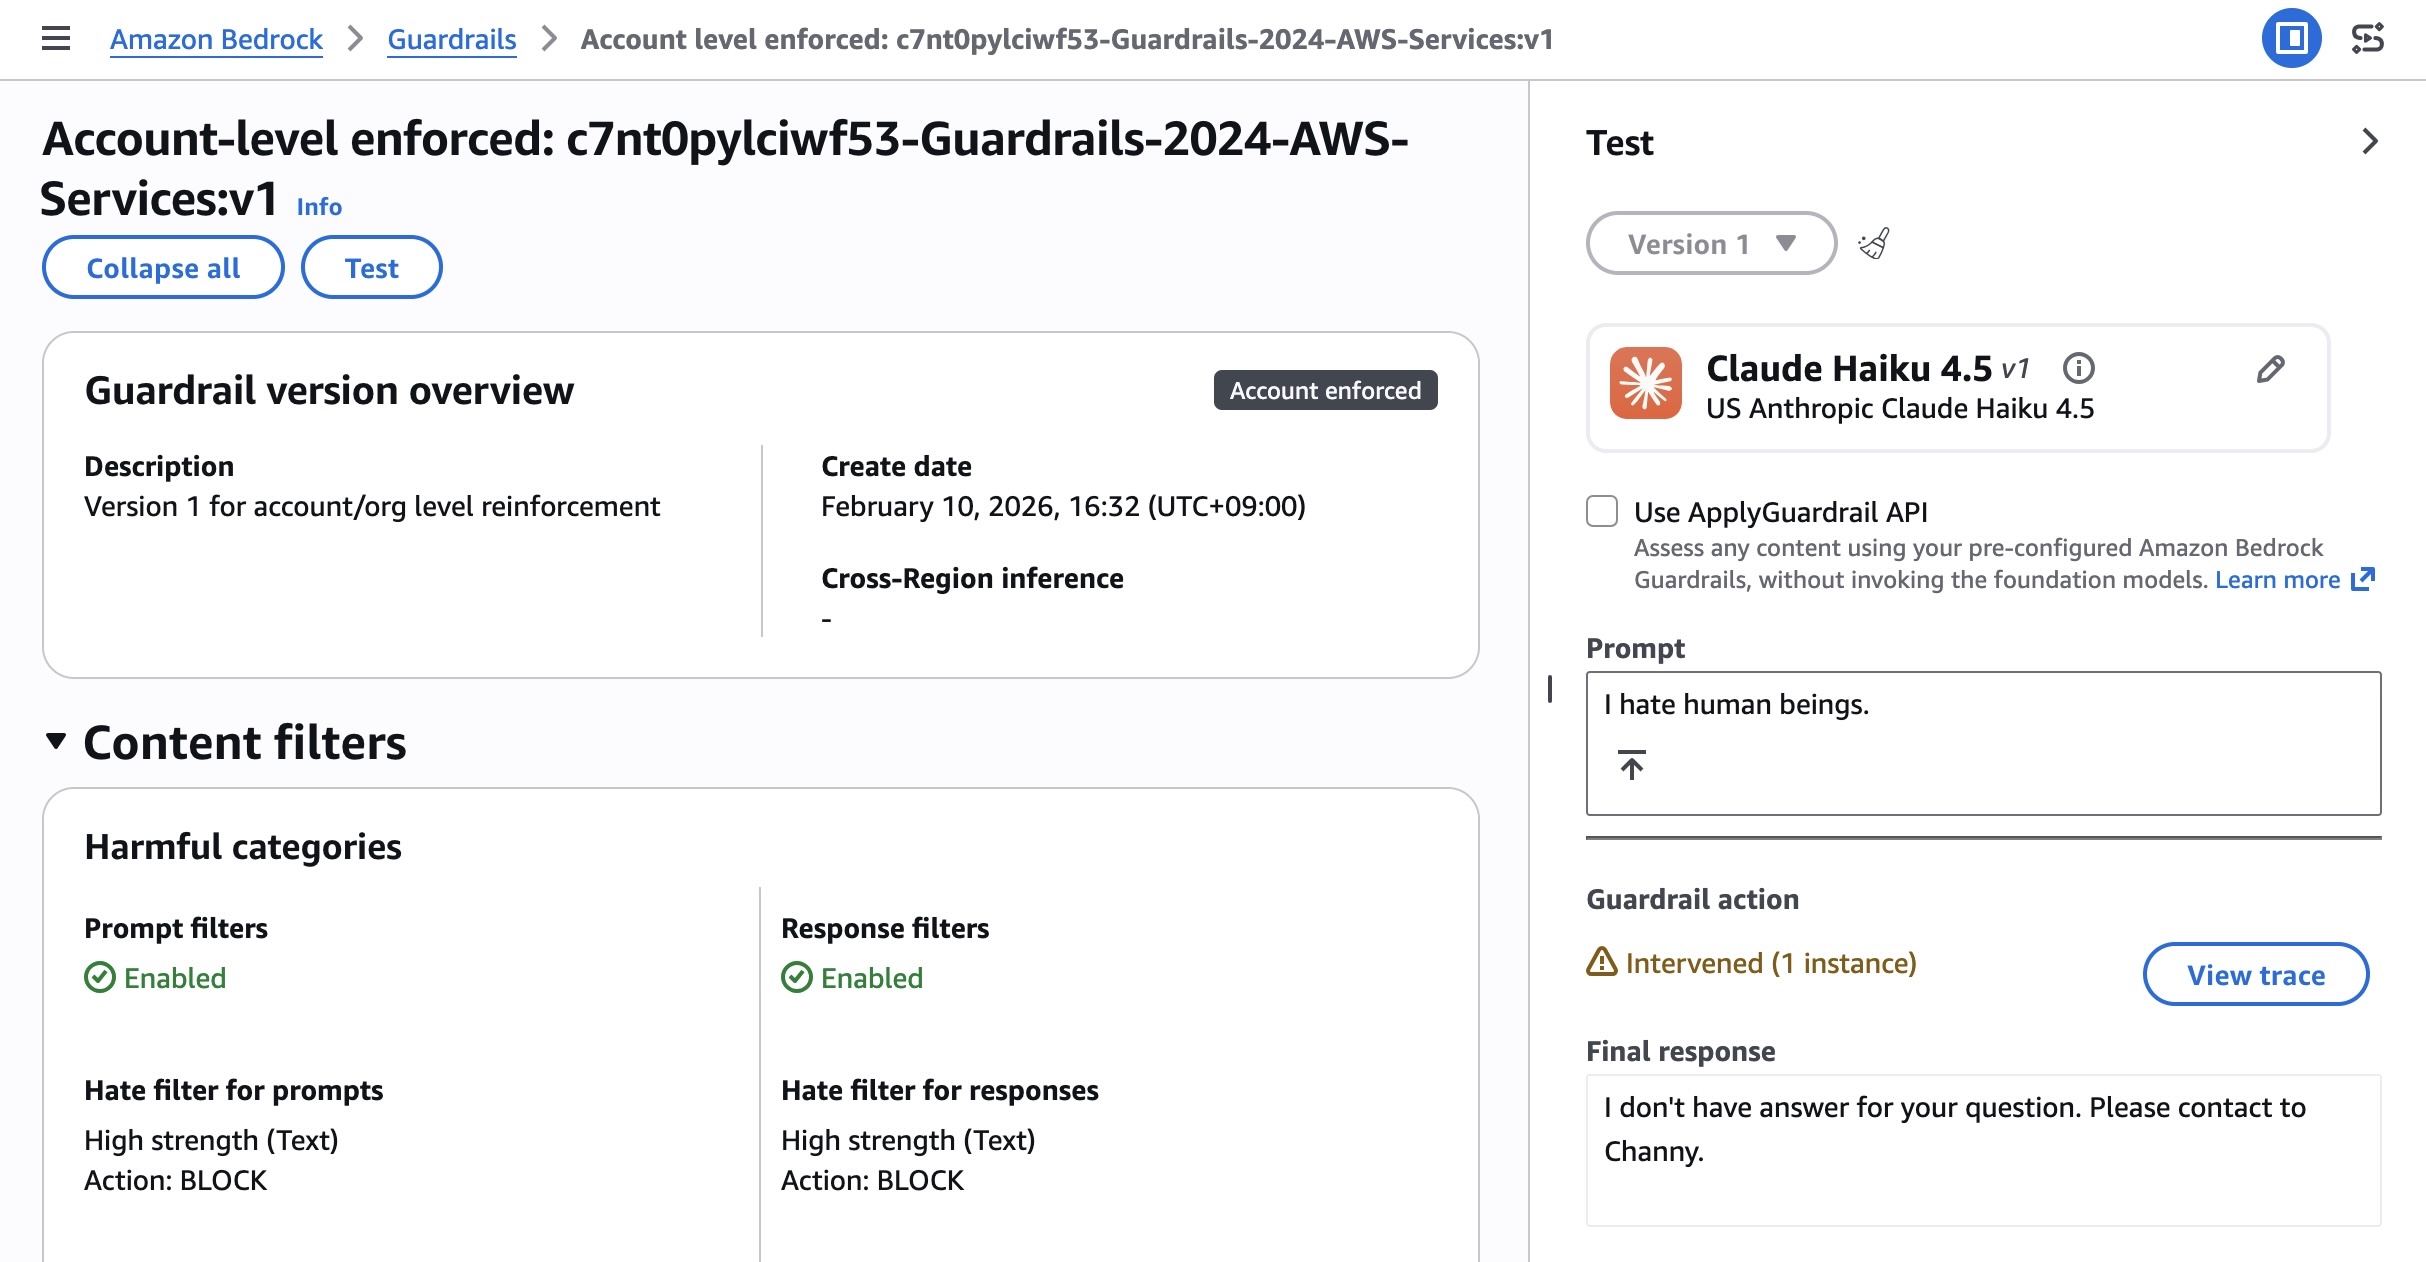
After creating the enforcement, you can test and verify enforcement using a role in your account. The account-enforced guardrail should automatically apply to both prompts and outputs.
Check the response for guardrail assessment information. The guardrail response will include enforced guardrail information. You can also test by making a Bedrock inference call using InvokeModel, InvokeModelWithResponseStream, Converse, or ConverseStream APIs.
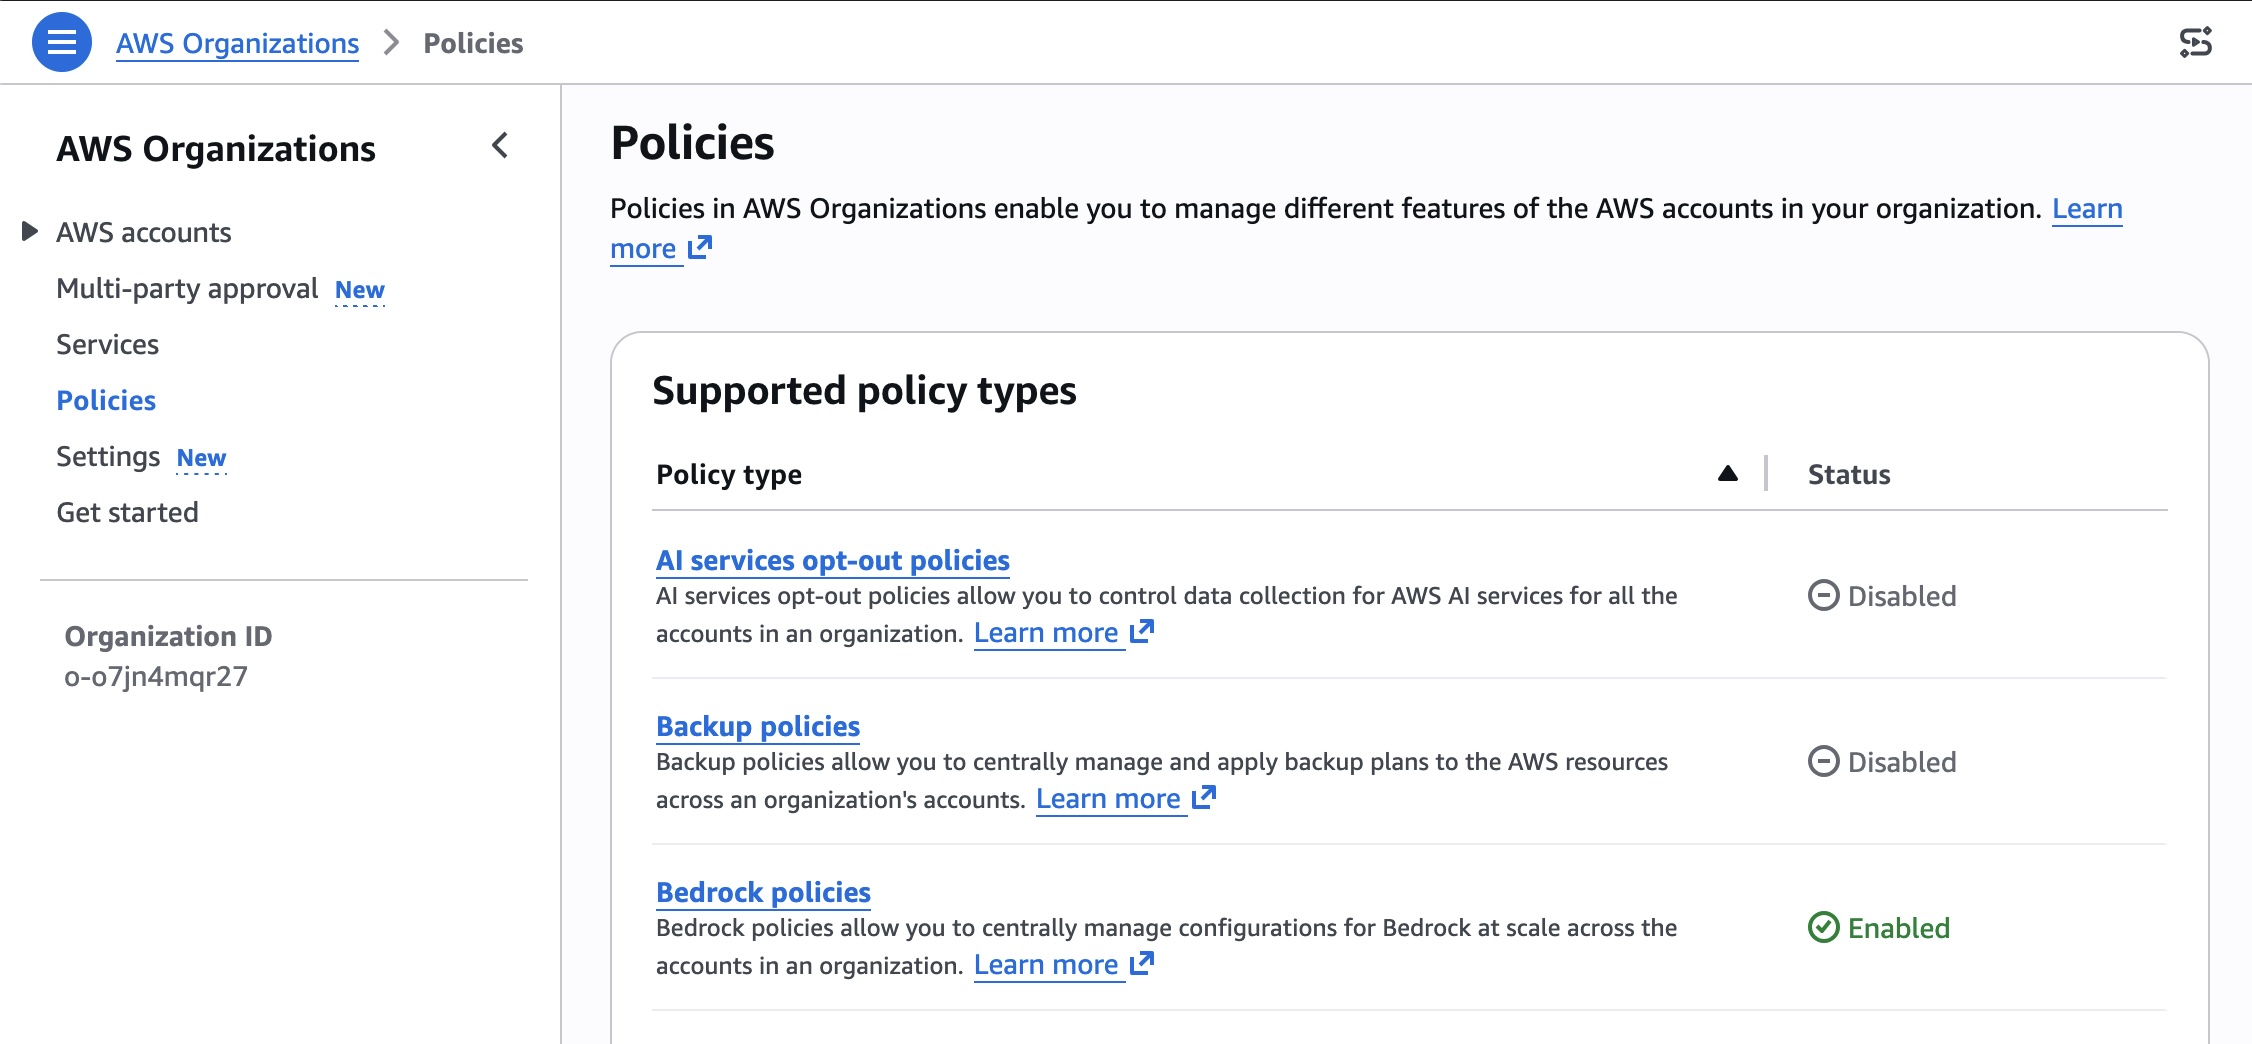
To enable organization-level enforcement, go to AWS Organizations console and choose Policies menu. You can enable the Bedrock policies in the console.
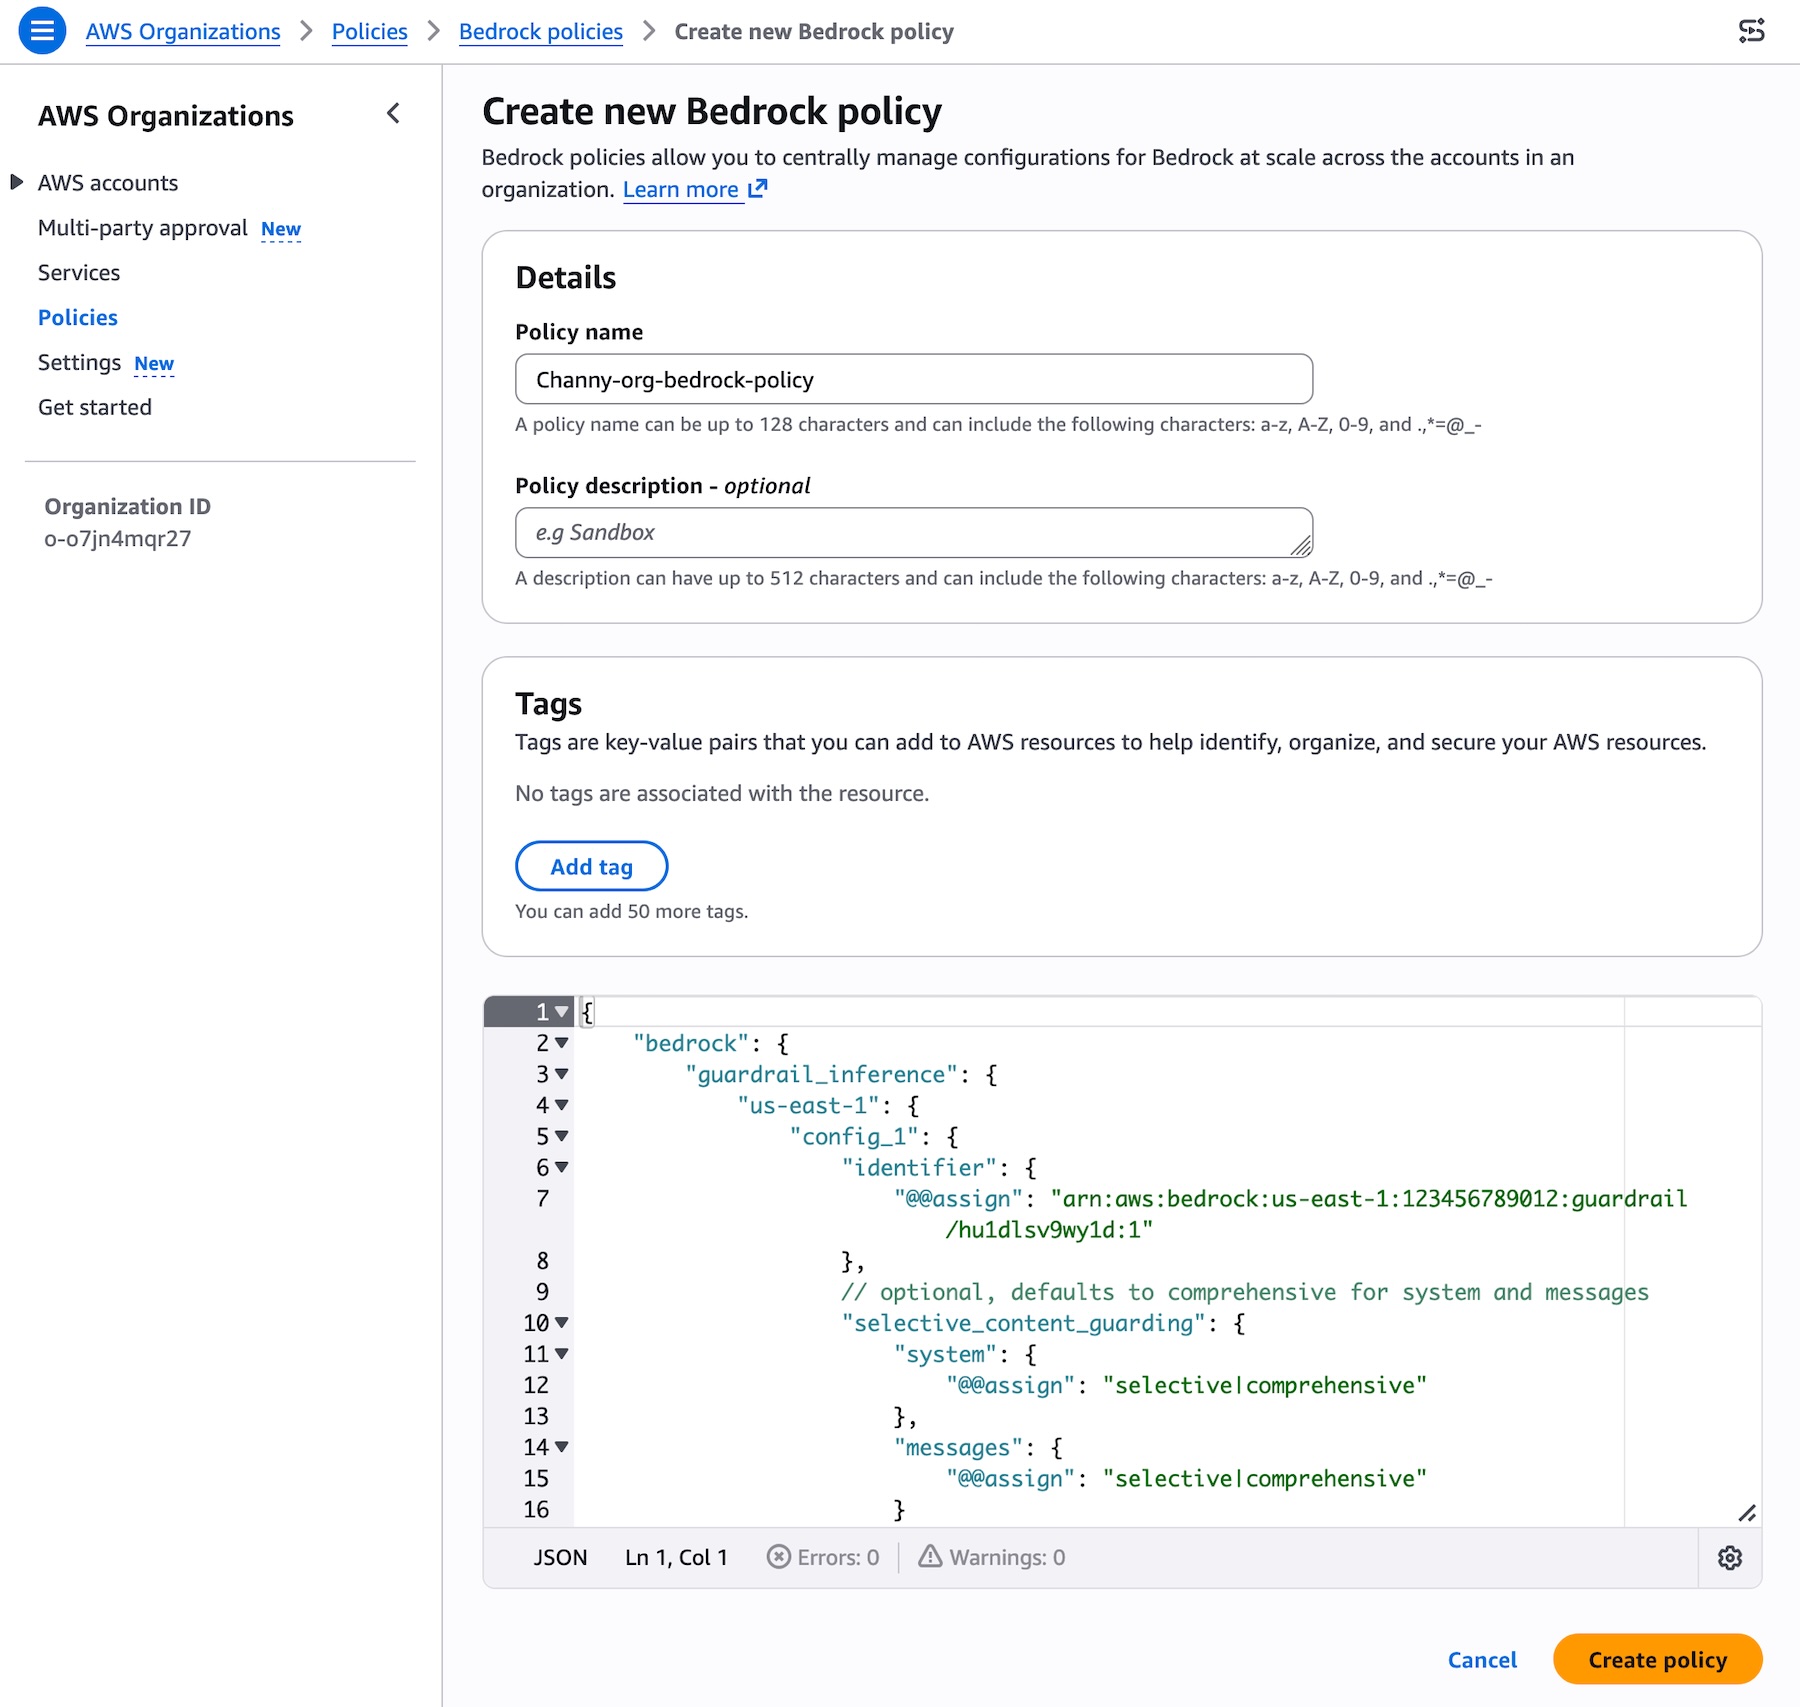
You can create a Bedrock policy that specifies your guardrail and attach it to your target accounts or OUs. Choose Bedrock policies enabled and Create policy. Specify your guardrail ARN and version and configure the input tags setting for in the AWS Organizations. To learn more, visit Amazon Bedrock policies in AWS Organizations and Amazon Bedrock policy syntax and examples.
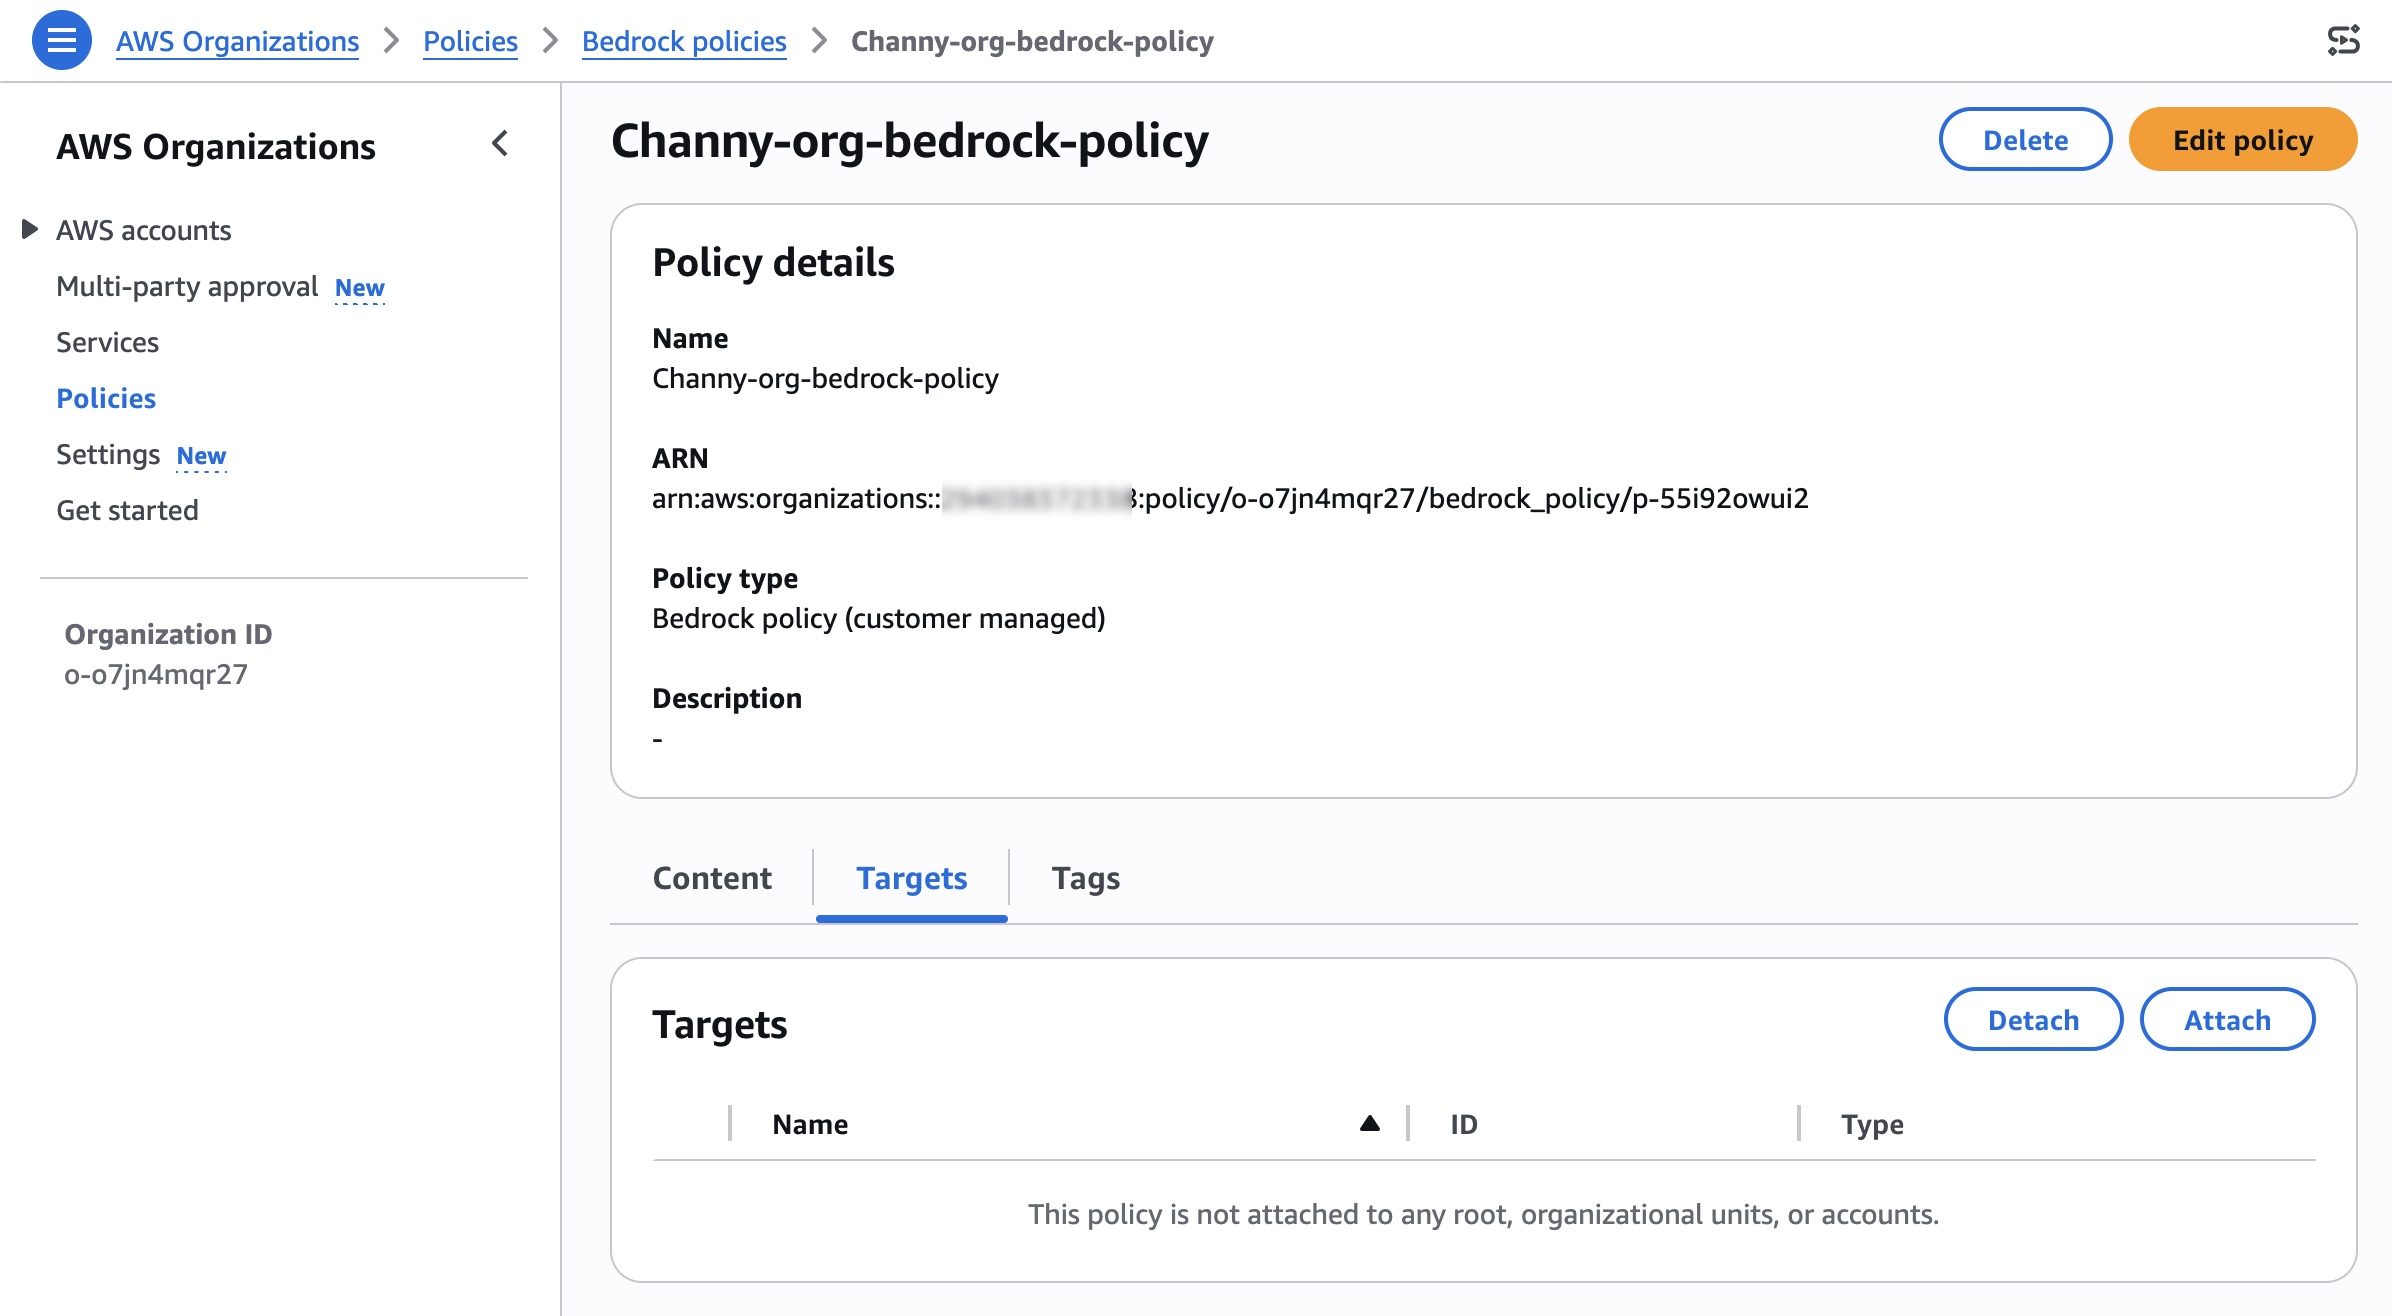
After creating the policy, you can attach the policy to your desired organizational units, accounts, root in the Targets tab.
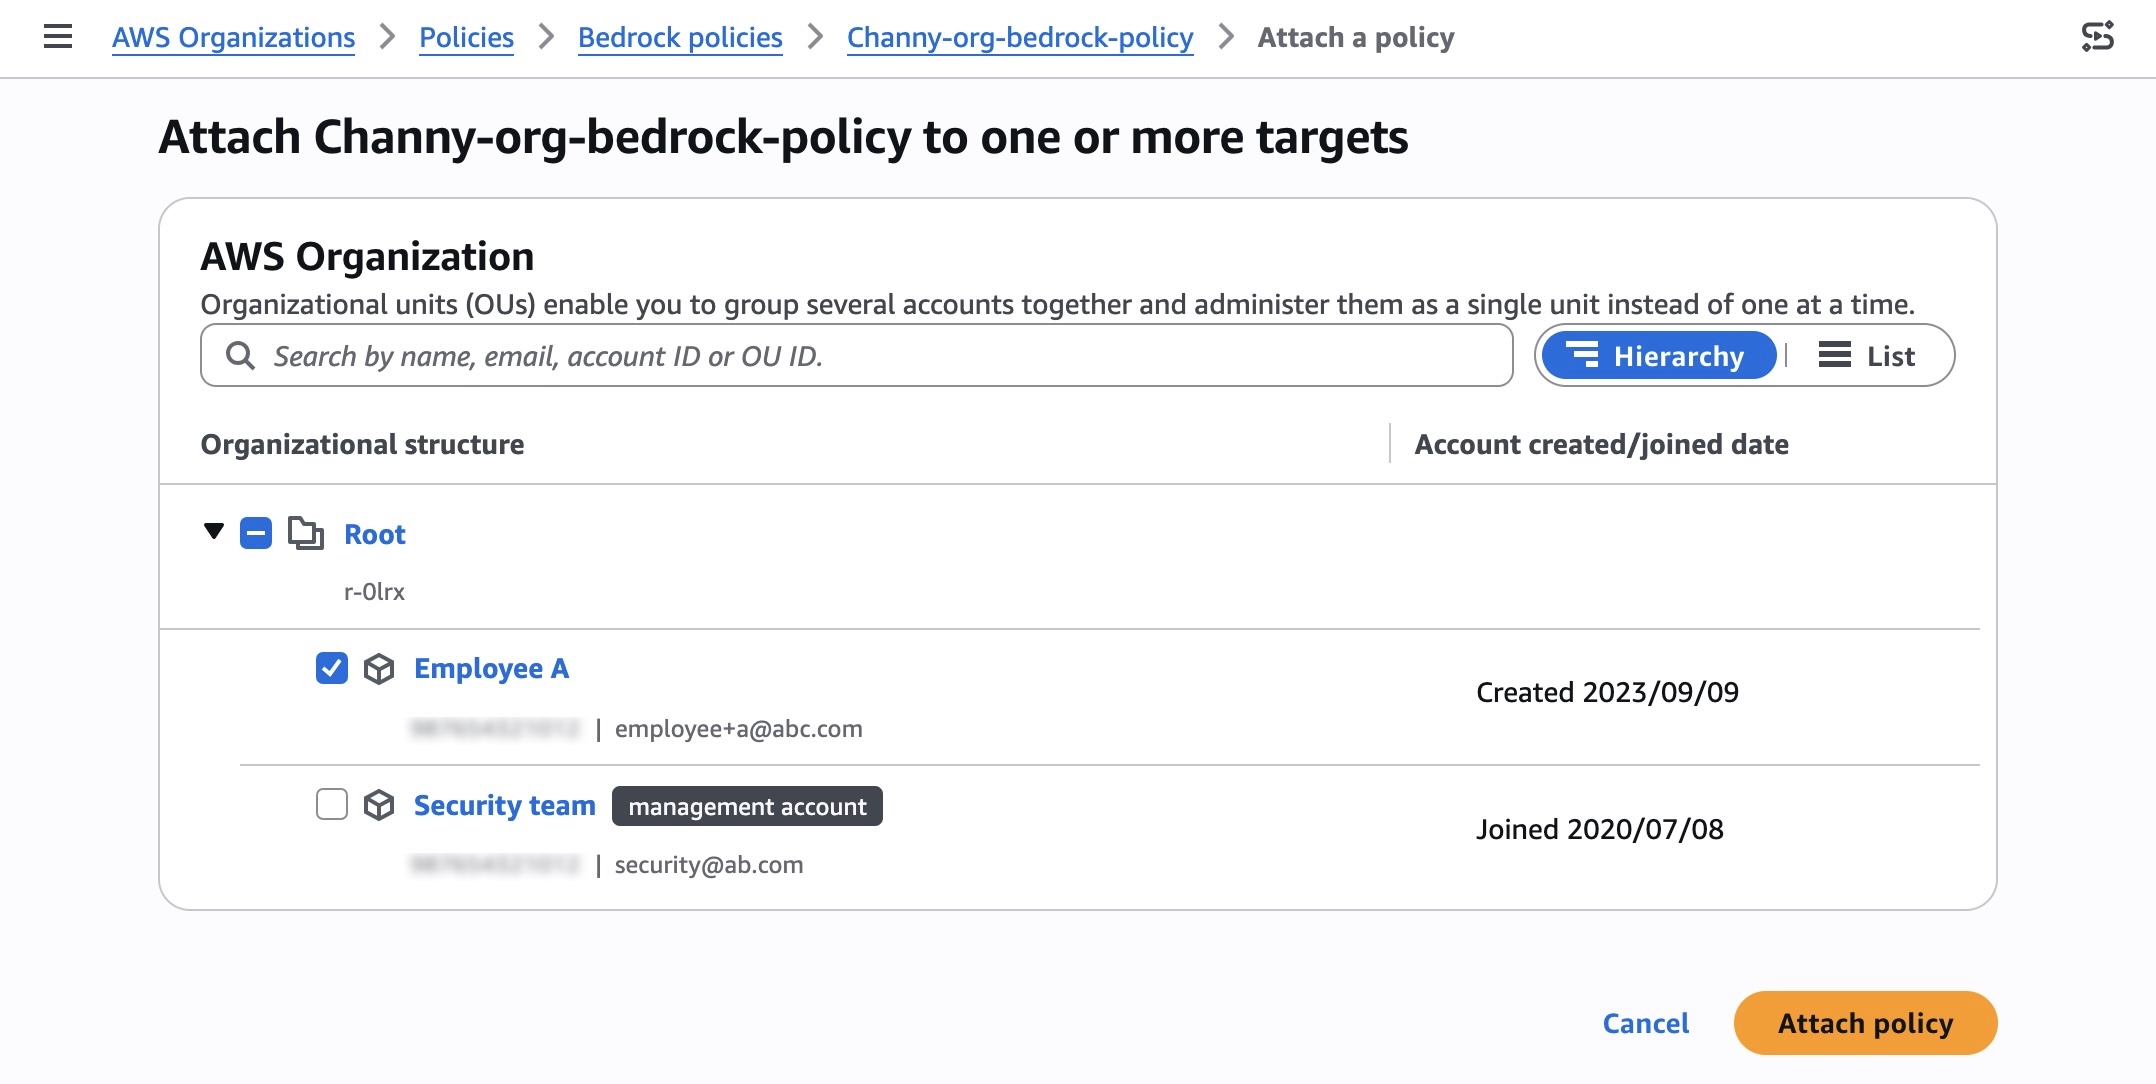
Search and select your organization root, OUs, or individual accounts to attach your policy, and choose Attach policy.
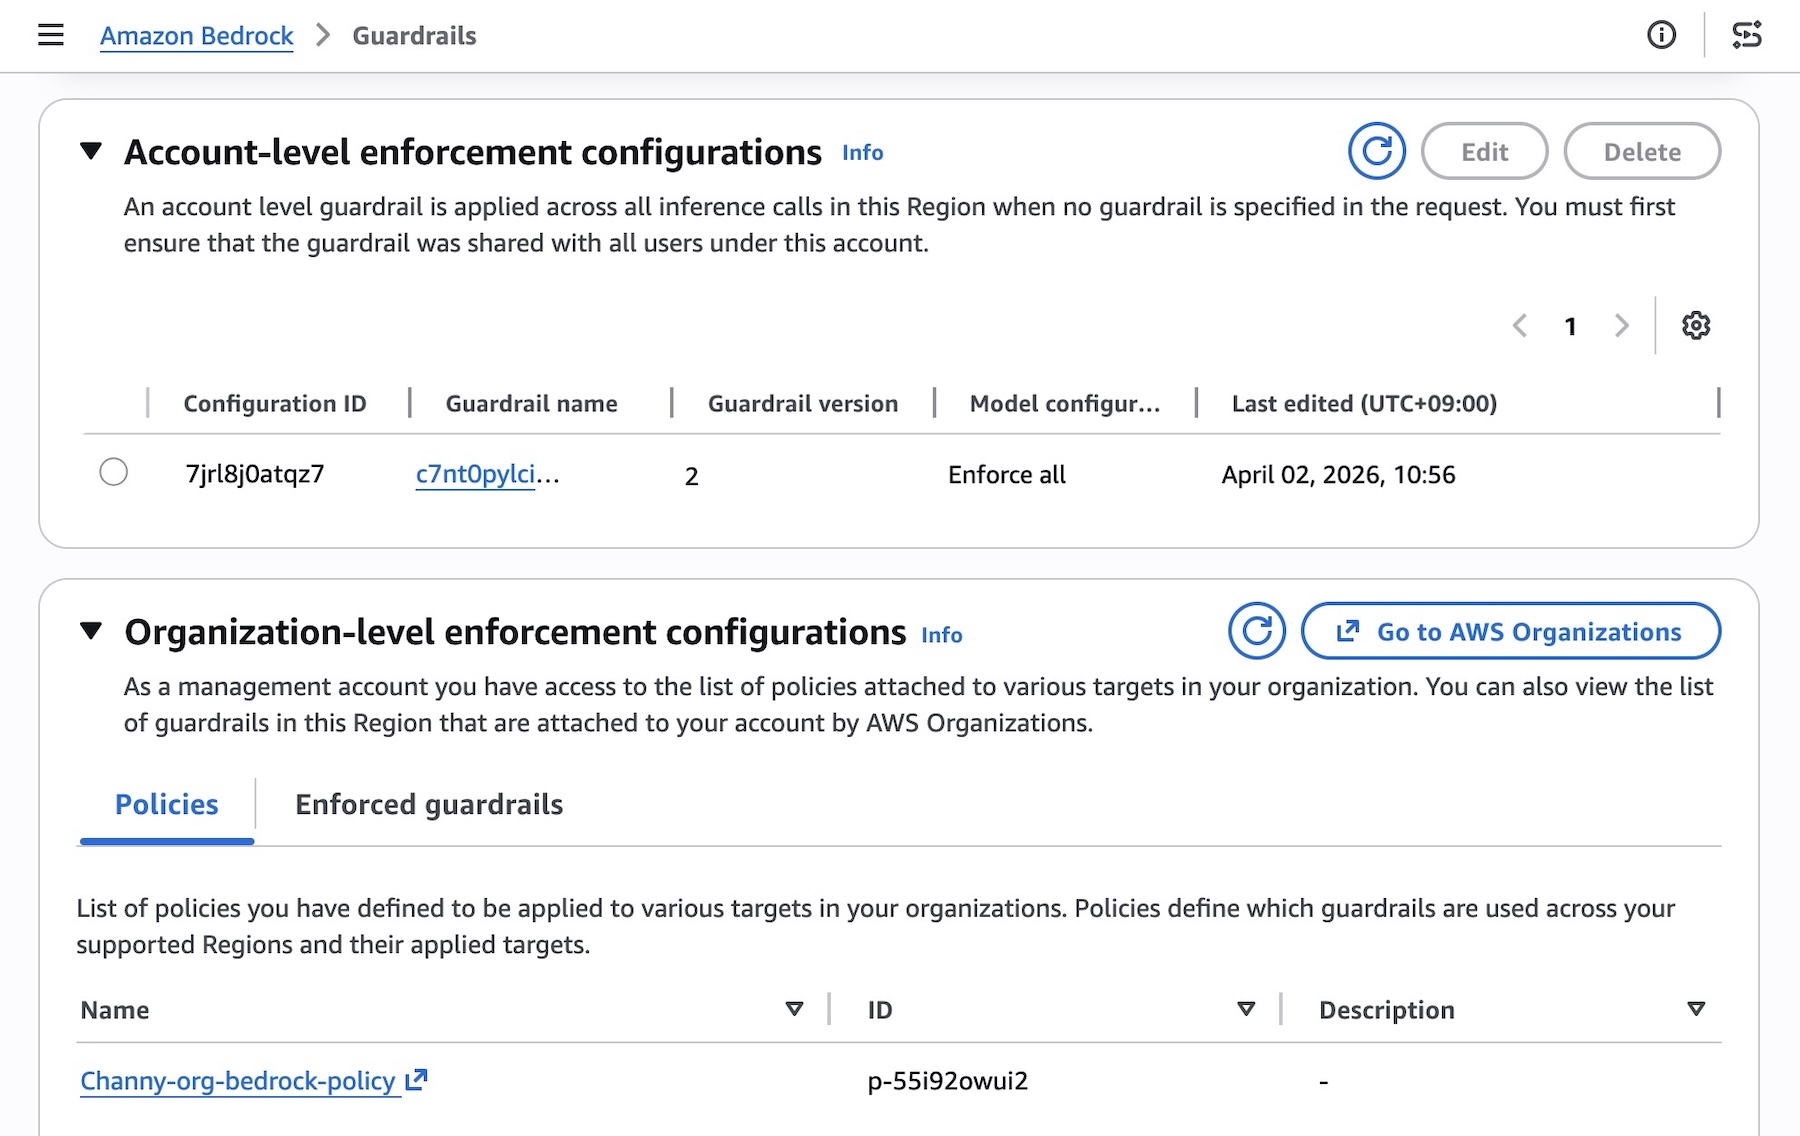
You can test that the guardrail is being enforced on member accounts and verify which guardrail is enforced. From a member account attached, you should see the organization enforced guardrail under the section Organization-level enforcement configurations.
The underlying safeguards within the specified guardrail are then automatically enforced for every model inference request across all member entities, ensuring consistent safety controls. To accommodate varying requirements of individual teams or applications, you can attach different policies with associated guardrails to different member entities through your organization.
Things to know Here are key considerations to know about GA features:
You can now choose to include or exclude specific models in Bedrock for inference, enabling centralized enforcement on model invocation calls. You can also choose to safeguard partial or complete system prompts and input prompts. To learn more, visit Apply cross-account safeguards with Amazon Bedrock Guardrails enforcement.
Ensure you are specifying the accurate guardrail Amazon Resource Names (ARN) in the policy. Specifying an incorrect or invalid ARN will result in policy violations, non-enforcement of safeguards, and the inability to use the models in Amazon Bedrock for inference. To learn more, visit Best practices for using Amazon Bedrock policies.
Automated Reasoning checks are not supported with this capability.
Now available Cross-account safeguards in Amazon Bedrock Guardrails is generally available today in the all AWS commercial and GovCloud Regions where Bedrock Guardrails is available. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. Charges apply to each enforced guardrail according to its configured safeguards. For detailed pricing information on individual safeguards, visit Amazon Bedrock Pricing page.
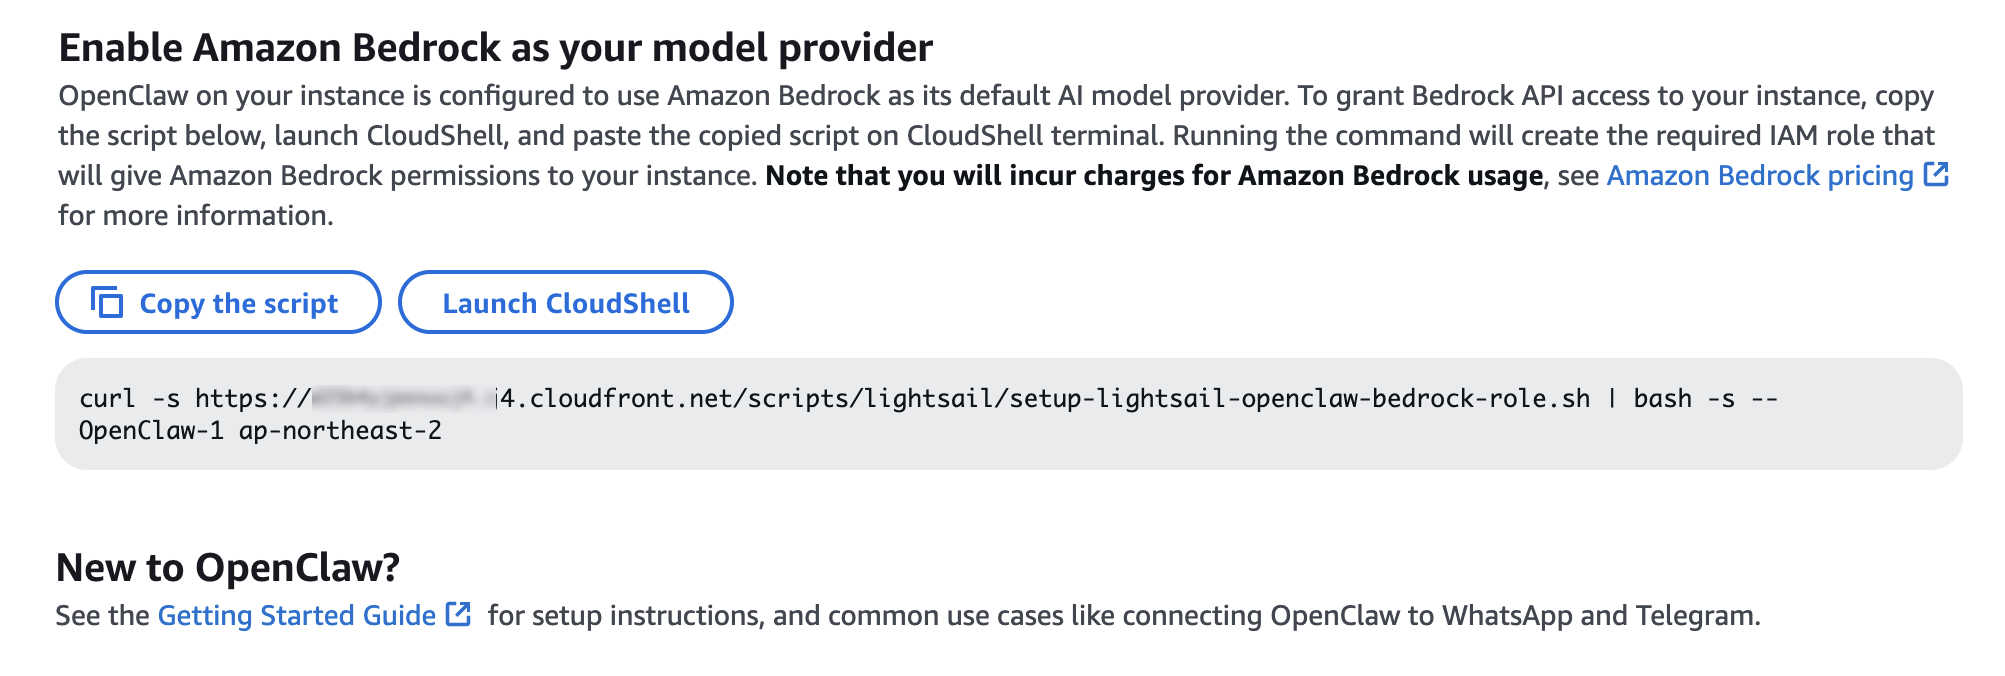
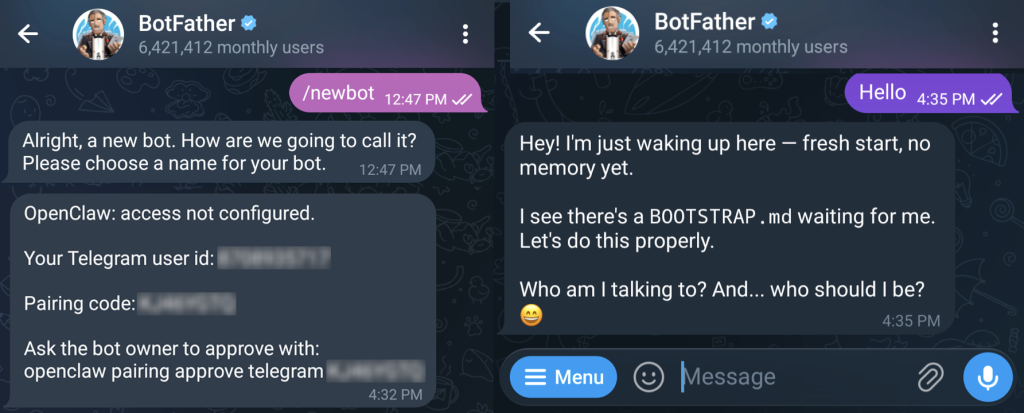
Today, we’re announcing the general availability of OpenClaw on Amazon Lightsail to launch OpenClaw instance, pairing your browser, enabling AI capabilities, and optionally connecting messaging channels. Your Lightsail OpenClaw instance is pre-configured with Amazon Bedrock as the default AI model provider. Once you complete setup, you can start chatting with your AI assistant immediately — no additional configuration required.
OpenClaw is an open-source self-hosted autonomous private AI agent that acts as a personal digital assistant by running directly on your computer. You can AI agents on OpenClaw through your browser to connect to messaging apps like WhatsApp, Discord, or Telegram to perform tasks such as managing emails, browsing the web, and organizing files, rather than just answering questions.
AWS customers have asked if they can run OpenClaw on AWS. Some of them blogged about running OpenClaw on Amazon EC2 instances. As someone who has experienced installing OpenClaw directly on my home device, I learned that this is not easy and that there are many security considerations.
So, let me introduce how to launch a pre-configured OpenClaw instance on Amazon Lightsail more easily and run it securely.
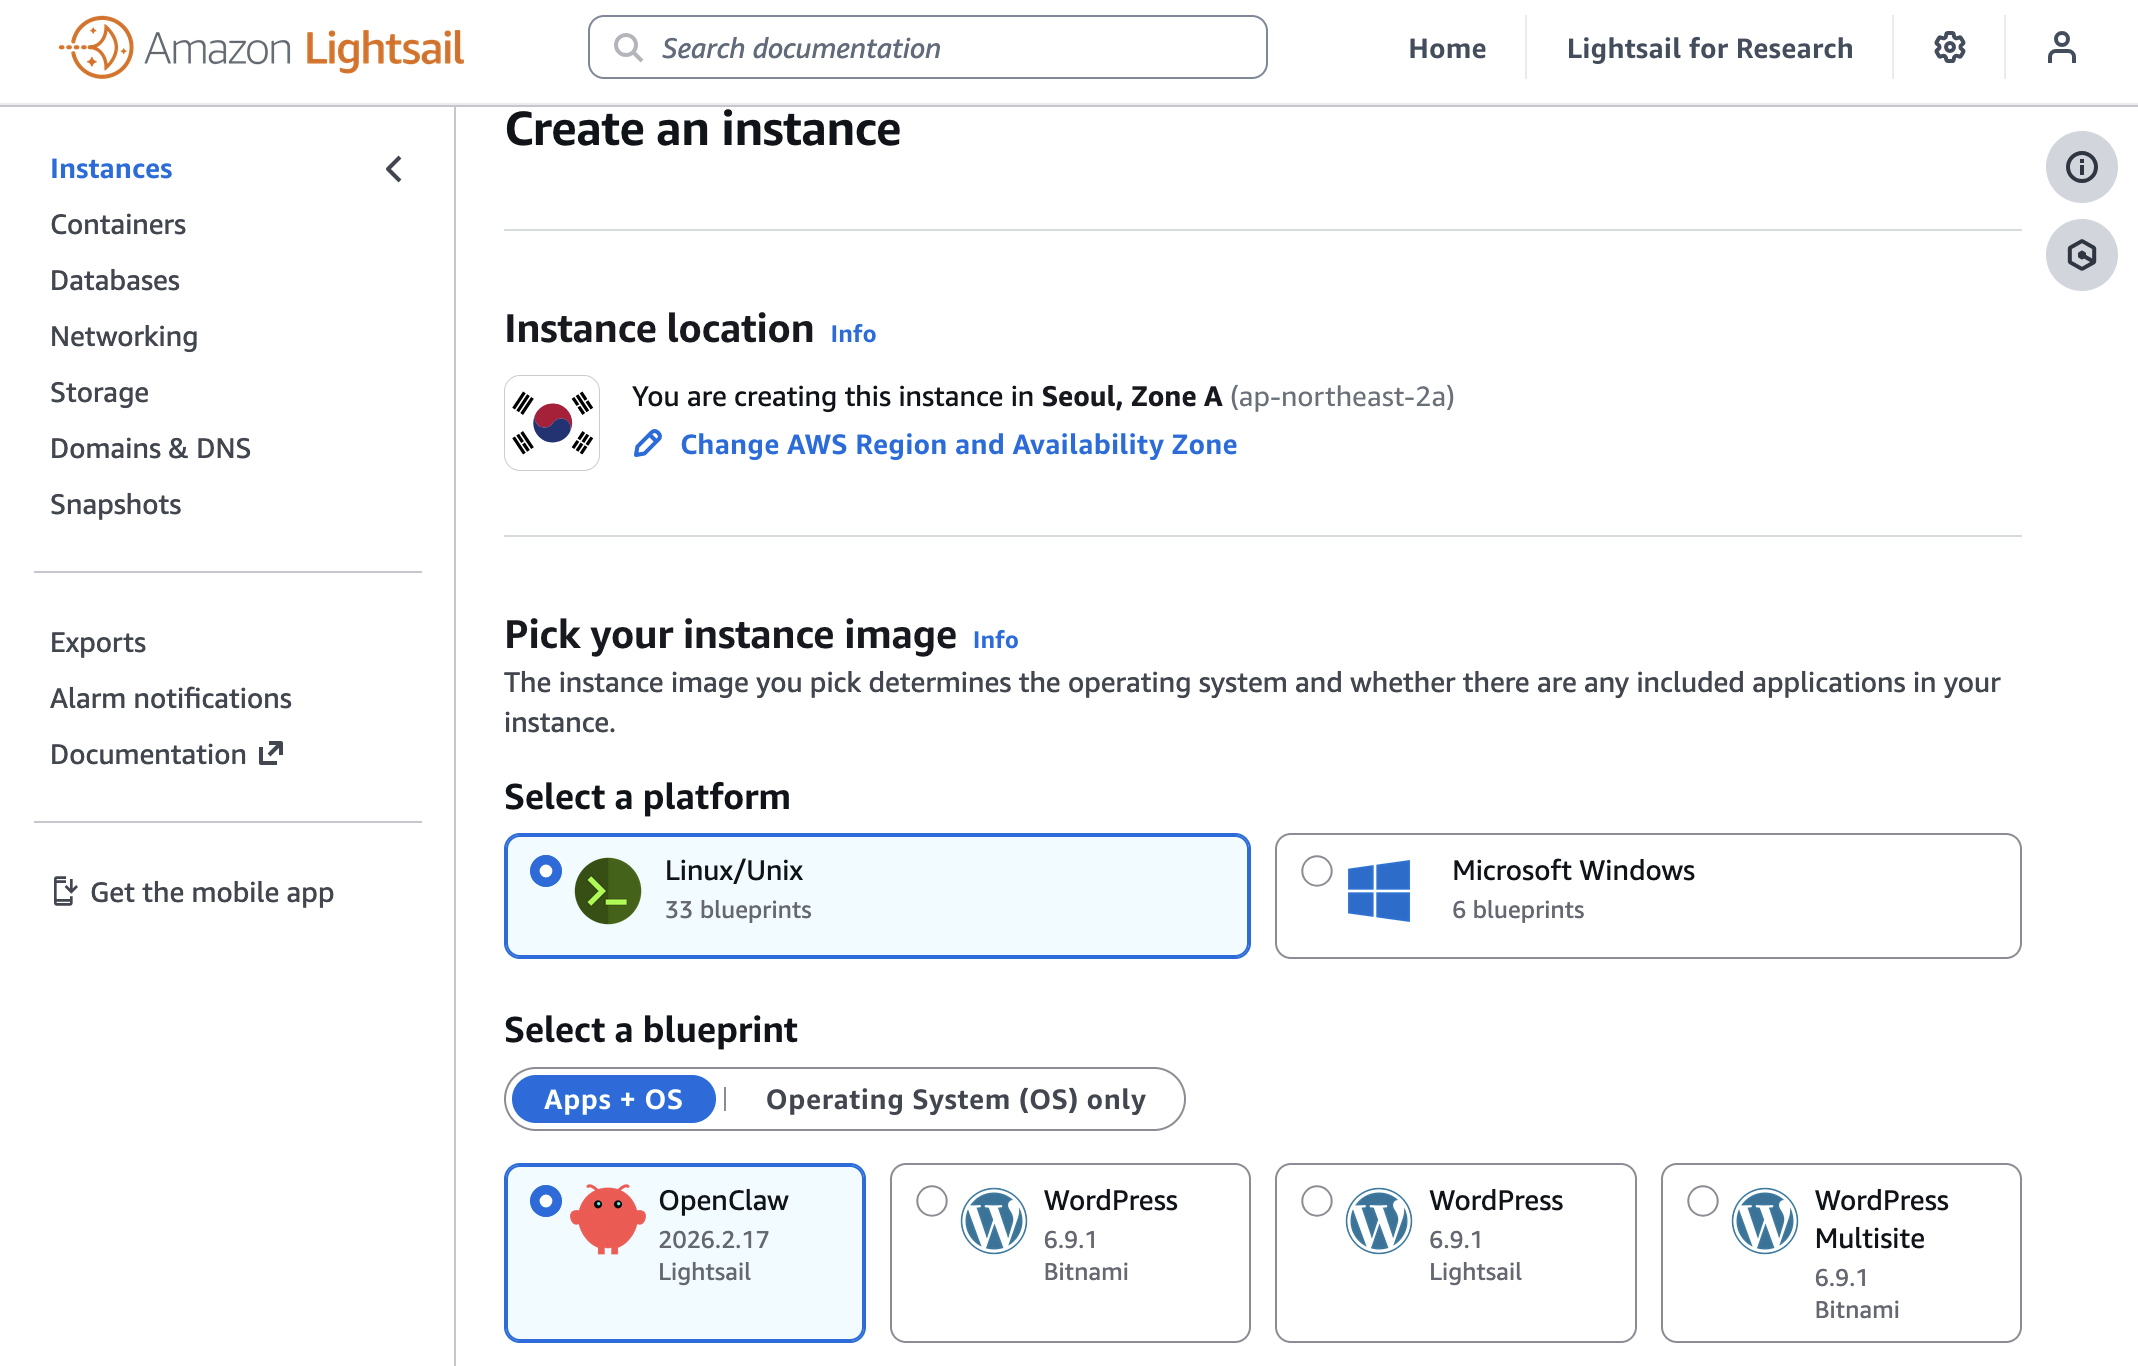
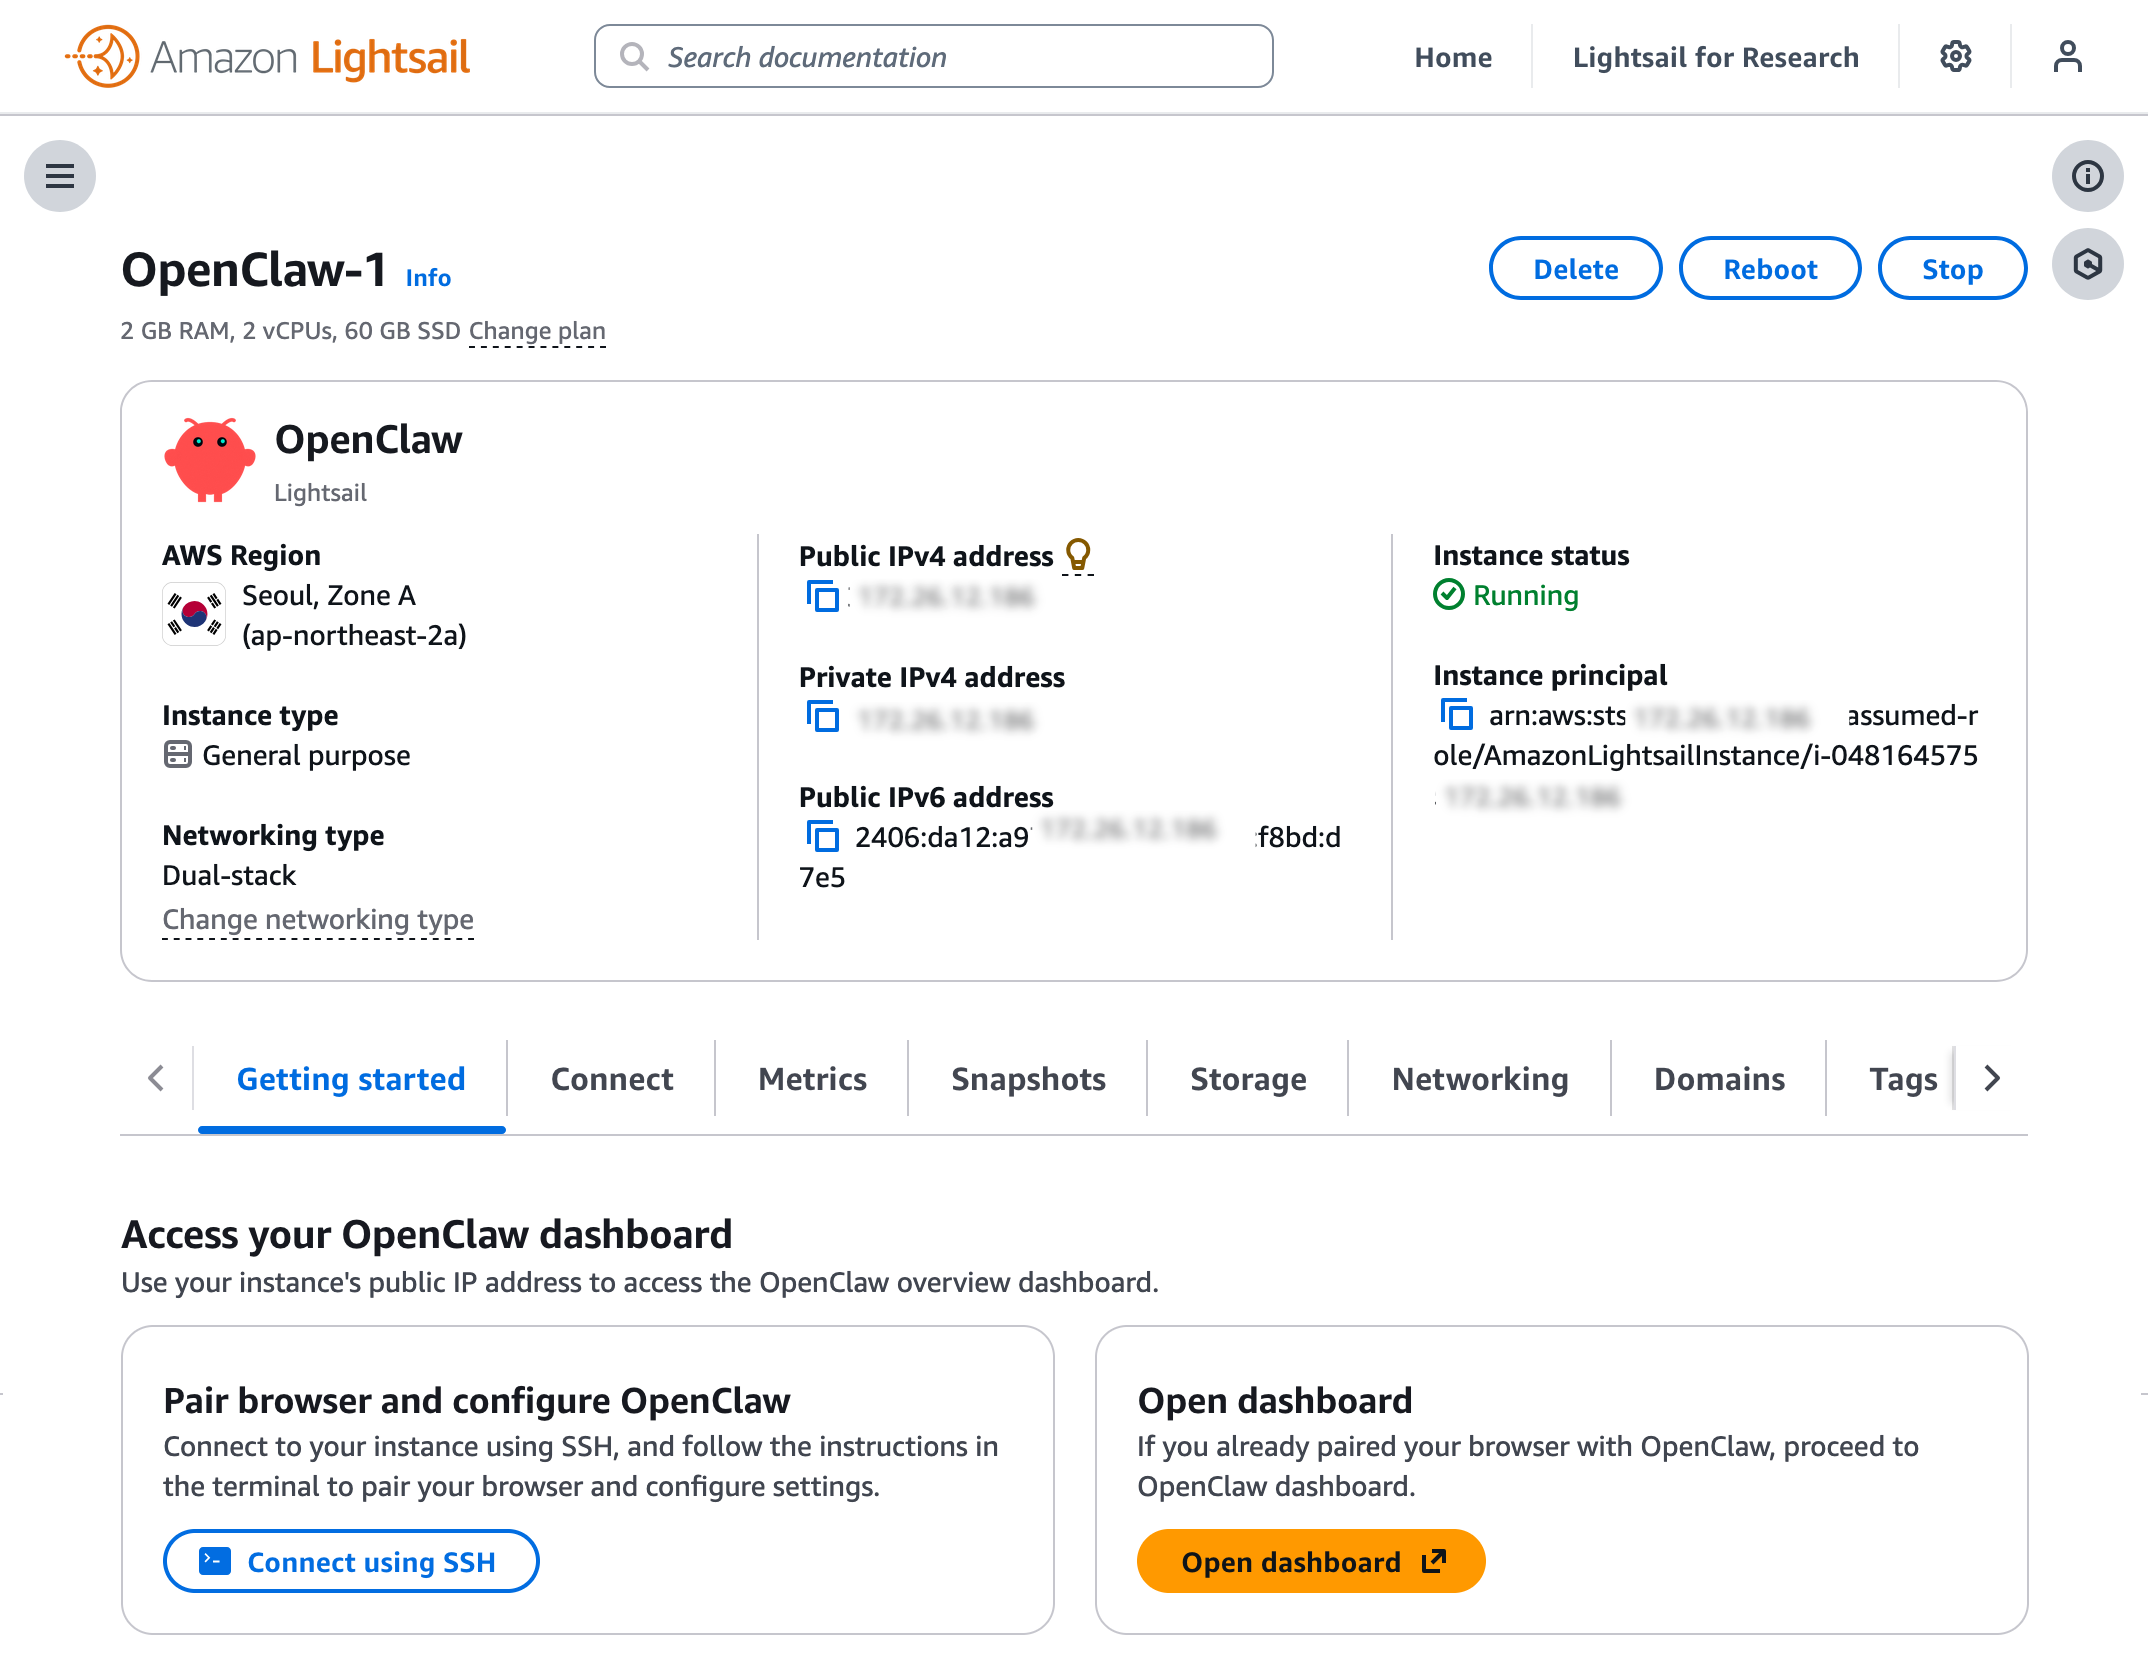
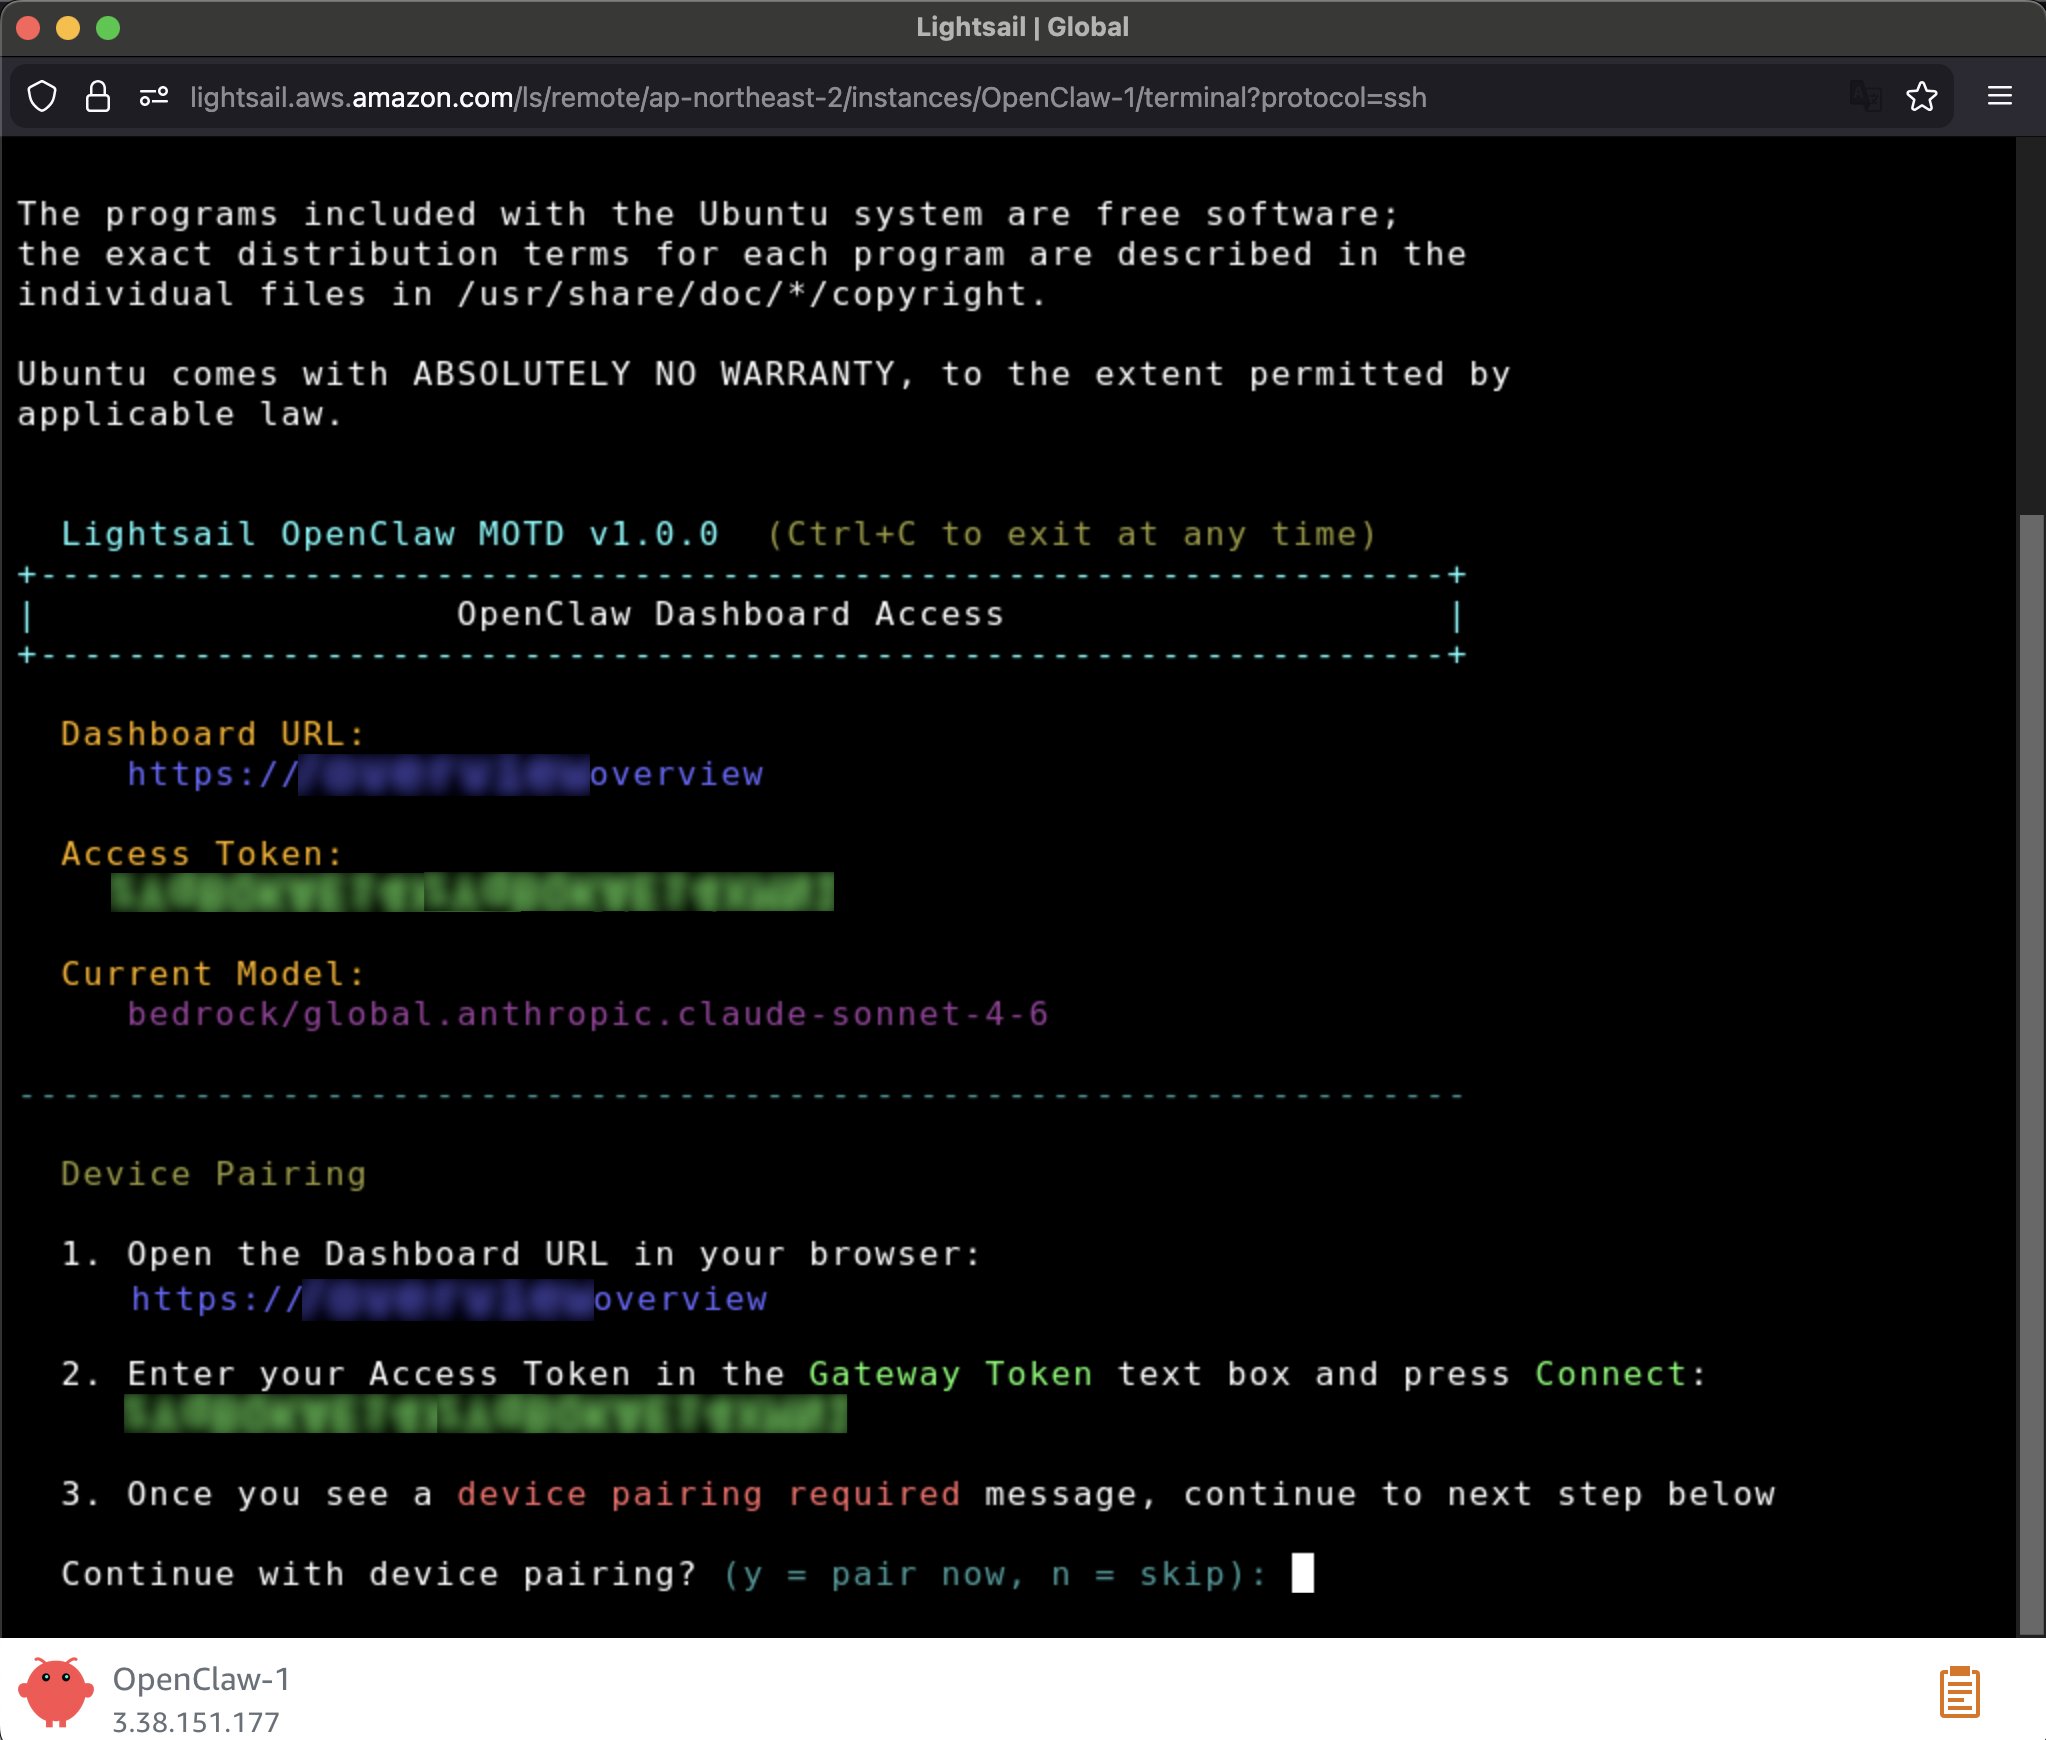
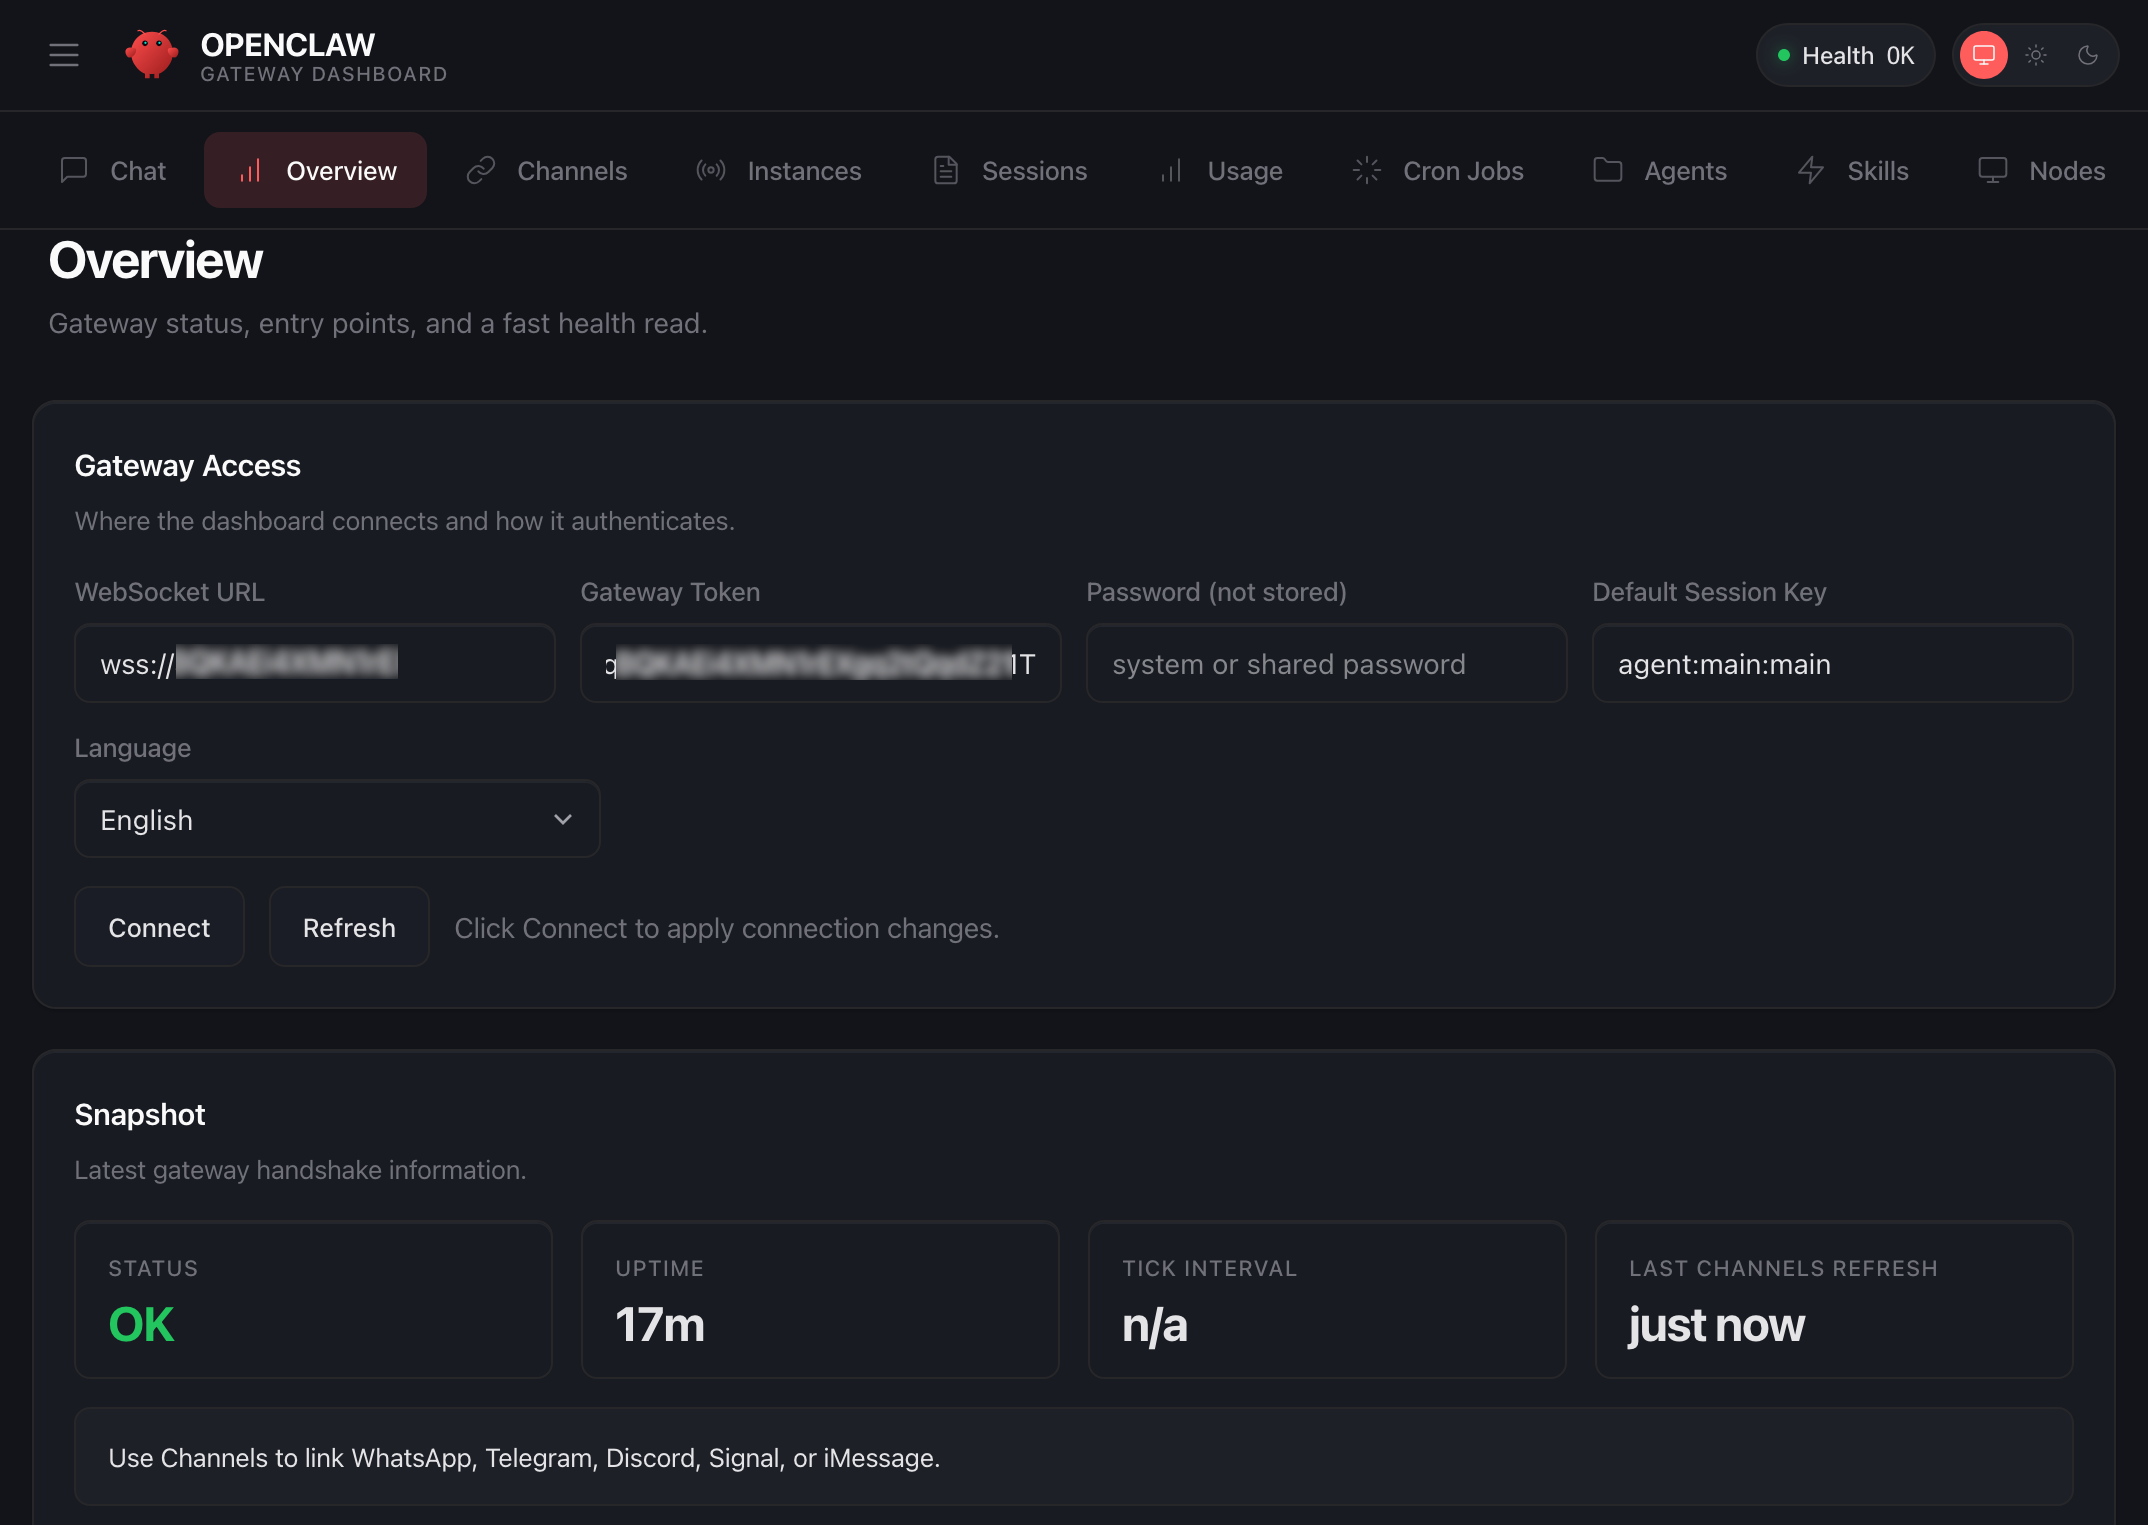
OpenClaw on Amazon Lightsail in action To get started, go to the Amazon Lightsail console and choose Create instance on the Instances section. After choosing your preferred AWS Region and Availability Zone, Linux/Unix platform to run your instance, choose OpenClaw under Select a blueprint.
You can choose your instance plan (4 GB memory plan is recommended for optimal performance) and enter a name for your instance. Finally choose Create instance. Your instance will be in a Running state in a few minutes.
Before you can use the OpenClaw dashboard, you should pair your browser with OpenClaw. This creates a secure connection between your browser session and OpenClaw. To pair your browser with OpenClaw, choose Connect using SSH in the Getting started tab.
When a browser-based SSH terminal opens, you can see the dashboard URL, security credentials displayed in the welcome message. Copy them and open the dashboard in a new browser tab. In the OpenClaw dashboard, you can paste the copied access token into the Gateway Token field in the OpenClaw dashboard.
When prompted, press y to continue and a to approve with device pairing in the SSH terminal. When pairing is complete, you can see the OK status in the OpenClaw dashboard and your browser is now connected to your OpenClaw instance.
Your OpenClaw instance on Lightsail is configured to use Amazon Bedrock to power its AI assistant. To enable Bedrock API access, copy the script in the Getting started tab and run copied script into the AWS CloudShell terminal.
Once the script is complete, go to Chat in the OpenClaw dashboard to start using your AI assistant!
You can set up OpenClaw to work with messaging apps like Telegram and WhatsApp for interacting with your AI assistant directly from your phone or messaging client. To learn more, visit Get started with OpenClaw on Lightsail in the Amazon Lightsail User Guide.
Things to know Here are key considerations to know about this feature:
Permission — You can customize AWS IAM permissions granted to your OpenClaw instance. The setup script creates an IAM role with a policy that grants access to Amazon Bedrock. You can customize this policy at any time. But, you should be careful when modifying permissions because it may prevent OpenClaw from generating AI responses. To learn more, visit AWS IAM policies in the AWS documentation
Cost — You pay for the instance plan you selected on an on-demand hourly rate only for what you use. Every message sent to and received from the OpenClaw assistant is processed through Amazon Bedrock using a token-based pricing model. If you select a third-party model distributed through AWS Marketplace such as Anthropic Claude or Cohere, there may be additional software fees on top of the per-token cost.
Security — Running a personal AI agent on OpenClaw is powerful, but it may cause security threat if you are careless. I recommend to hide your OpenClaw gateway never to expose it to open internet. The gateway auth token is your password, so rotate it often and store it in your envirnment file not hardcoded in config file. To learn more about security tips, visit Security on OpenClaw gateway.
This post is cowritten by Julio Bando from Santander.
Santander faced a significant technical challenge in managing an infrastructure that processes billions of daily transactions across more than 200 critical systems. The expansion into diverse financial services, including investment banking, wealth management, insurance, and payment solutions, had created unprecedented technological complexity, requiring a robust, agile, and scalable infrastructure solution. This raised two main issues. Santander needed to ensure that provisioned services followed established architecture definitions, and they needed to reduce infrastructure provisioning time, which took up to 90 days. This situation demanded intensive operational effort. The solution emerged through an innovative platform engineering initiative called Catalyst, which transformed the bank’s cloud infrastructure and development management. This post analyzes the main cases, benefits, and results obtained with this initiative.
The Catalyst solution
Santander is a global financial services company present in more than 10 countries, with over 160 million customers worldwide. They conceived Catalyst in conjunction with the Platform Strategy Program (PSP), an Amazon Web Services (AWS) program specialized in infrastructure platform design. Implemented through a partnership between AWS Professional Services and Santander, the platform was designed to abstract infrastructure provisioning complexity, standardize architectural compliance, and create a framework that enables new technologies in the bank.
The platform’s in-house frontend was developed as an intuitive developer portal, offering a unified interface for all provisioning and resource management needs. At the platform’s core is the control plane cluster, based on Amazon Elastic Kubernetes Service (Amazon EKS). This cluster is the brain of the operation, orchestrating all components and workflows. Within the cluster, Crossplane plays a fundamental role, acting as a universal resource provisioner that Santander uses to manage resources across multiple cloud providers consistently and declaratively.
The control plane cluster has three components:
Data plane claims – Managed by ArgoCD, a continuous delivery tool, the component is responsible for continuous synchronization and deployment of application stacks (integrated sets of cloud resources) and configurations, exploring the GitOps concept.
Policies catalog – A central repository of policies ensuring compliance and security across all operations using Open Policy Agent (OPA).
Santander used this innovative architecture to significantly reduce provisioning time from 90 days to only a few hours and in some cases only minutes. Catalyst brought significant benefits in terms of standardization, security, and governance. The provisioning cycle decreased from 30 days to 2 days, and proof of concept preparation time jumped from 90 days to only 1 hour. The consolidation of over 100 pipelines into a single control plane will further simplify infrastructure management. The following diagram shows the Santander catalyst architecture.
Key platform capabilities
Catalyst’s implementation enabled the creation of strategic workloads demonstrating the platform’s versatility and robustness:
Generative AI agents stack – The first success case was implementing a complete stack for AI agents integrating:
Modern data platform – One of the most complex workloads implemented through Catalyst was the new data platform, including:
Built-in integration with Databricks
Data lakes
Automated extract, transform, and load (ETL) workflows
Integration with centralized data catalog
Segregated environments for experimentation. With this implementation, the bank significantly reduces approximately 3,000 monthly tickets related to data experimentation environment provisioning.
Cloud process orchestration – creation of a modern process orchestration environment with significant results:
Implementation of retry patterns and error handling
Centralized process monitoring
Overall result
This stack reduced AI agent implementation time from 105 days to only 24 hours, eliminating dozens of provisioning tickets per environment. The success of these workloads demonstrates Catalyst’s technical capability and the solution’s versatility in meeting different business needs. Each implementation brought valuable learnings that were incorporated into the platform, creating a virtuous cycle of continuous improvement. The variety of implemented workloads also shows how Catalyst has the potential to be a universal platform, capable of supporting everything from traditional use cases to the most innovative ones involving AI and legacy system modernization. Catalyst’s success wasn’t limited to operational efficiency. The platform also catalyzed a cultural change within Santander, promoting an automation and self-service mindset among development teams. This resulted in faster overall development velocity, more agile teams, and enhanced capability to respond quickly to market changes.
Conclusion
Catalyst represents more than merely a technological tool—it’s a digital transformation enabler that’s redefining cloud development standards at the bank. With the platform, Santander addressed the challenges of a scaled environment and established a solid foundation for continuous innovation and future growth.
With these practical cases, Santander proves that investment in platform engineering solves technical problems and enables new business possibilities, keeping the bank at the forefront of digital transformation in the financial sector.
Last week, my team met many developers at Developer Week in San Jose. My colleague, Vinicius Senger delivered a great keynote about renascent software—a new way of building and evolving applications where humans and AI collaborate as co-developers using Kiro. Other colleagues spoke about building and deploying production-ready AI agents. Everyone stayed to ask and hear the questions related to agent memory, multi-agent patterns, meta-tooling and hooks. It was interesting how many developers were actually building agents.
We are continuing to meet developers and hear their feedback at third-party developer conferences. You can meet us at the dev/nexus, the largest and longest-running Java ecosystem conference on March 4-6 in Atlanta. My colleague, James Ward will speak about building AI Agents with Spring and MCP, and Vinicius Senger and Jonathan Vogel will speak about 10 tools and tips to upgrade your Java code with AI. I’ll keep sharing places for you to connect with us.
Last week’s launches Here are some of the other announcements from last week:
Claude Sonnet 4.6 model in Amazon Bedrock – You can now use Claude Sonnet 4.6 which offers frontier performance across coding, agents, and professional work at scale. Claude Sonnet 4.6 approaches Opus 4.6 intelligence at a lower cost. It enables faster, high-quality task completion, making it ideal for high-volume coding and knowledge work use cases.
Amazon EC2 Hpc8a instances powered by 5th Gen AMD EPYC processors – You can use new Hpc8a instances delivering up to 40% higher performance, increased memory bandwidth, and 300 Gbps Elastic Fabric Adapter networking. You can accelerate compute-intensive simulations, engineering workloads, and tightly coupled HPC applications.
Amazon SageMaker Inference for custom Amazon Nova models – You can now configure the instance types, auto-scaling policies, and concurrency settings for custom Nova model deployments with Amazon SageMaker Inference to best meet your needs.
Nested virtualization on virtual Amazon EC2 instances – You can create nested virtual machines by running KVM or Hyper-V on virtual EC2 instances. You can leverage this capability for use cases such as running emulators for mobile applications, simulating in-vehicle hardware for automobiles, and running Windows Subsystem for Linux on Windows workstations.
Server-Side Encryption by default in Amazon Aurora – Amazon Aurora further strengthens your security posture by automatically applying server-side encryption by default to all new databases clusters using AWS-owned keys. This encryption is fully managed, transparent to users, and with no cost or performance impact.
Kiro in AWS GovCloud (US) Regions – You can use Kiro for the development teams behind government missions. Developers in regulated environments can now leverage Kiro’s agentic AI tool with the rigorous security controls required.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Additional updates Here are some additional news items that you might find interesting:
Introducing Agent Plugins for AWS – You can see how new open-source Agent Plugins for AWS extend coding agents with skills for deploying applications to AWS. Using the deploy-on-aws plugin, you can generate architecture recommendations, cost estimates, and infrastructure-as-code directly from your coding agent.
A chat with Byron Cook on automated reasoning and trust in AI systems – You can hear how to verify AI systems doing the right thing using automated reasoning when they generate code or manage critical decisions. Byron Cook’s team has spent a decade proving correctness in AWS and apply those techniques to agentic systems.
Best practices for deploying AWS DevOps Agent in production – You can read best practices for setting up DevOps Agent Spaces that balance investigation capability with operational efficiency. According to Swami Sivasubramanian, AWS DevOps Agent, a frontier agent that resolves and proactively prevents incidents, has handled thousands of escalations, with an estimated root cause identification rate of over 86% within Amazon.
From AWS community Here are my personal favorite posts from AWS community:
Let an AI Agent Do Your Job Searching – Still manually checking career pages during a job search? AWS Hero Danielle H. built an AI agent that does the work for you.
Building the AWS Serverless Power for Kiro – A former AWS Serverless Hero, Gunnar Grosch built a Kiro Power to integrate 25 MCP tools, ten steering guides, and structured decision guidance for the full development lifecycle.
Join the AWS Builder Center to connect with community, share knowledge, and access content that supports your development.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
Amazon Nova AI Hackathon – Join developers worldwide to build innovative generative AI solutions using frontier foundation models and compete for $40,000 in prizes across five categories including agentic AI, multimodal understanding, UI automation, and voice experiences during this six-week challenge from February 2nd to March 16th, 2026.
AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Ahmedabad (February 28), JAWS Days in Tokyo (March 7), Chennai (March 7), Slovakia (March 11), and Pune (March 21).
This improvement addresses a challenge in technical support workflow: when a support engineer receives a new customer case, the biggest bottleneck is often not diagnosing the problem but preparing the data. Customer logs arrive in different formats from multiple vendors, and each new log format typically requires manual integration and correlation before an investigation can begin. For simple cases, this process can take hours. For more complex investigations, it can take days, slowing resolution and reducing overall engineer productivity.
CyberArk is a global leader in identity security. Centered on intelligent privilege controls, it provides comprehensive security for human, machine, and AI identities across business applications, distributed workforces, and hybrid cloud environments.
In this post, we show you how CyberArk redesigned their support operations by combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock. You’ll learn how to simplify data processing flows, automate log parsing for diverse formats, and build autonomous investigation workflows that scale automatically.
To achieve these results, CyberArk needed a solution that could ingest customer logs, automatically structure them, establish relationships between related events, and make everything queryable in minutes, not days. The architecture had to be serverless to handle unpredictable support volumes, secure enough to protect customer Personally Identifiable Information (PII), and fast enough to allow same day case resolution.
The legacy architecture: Bottlenecks and manual workflows
When support engineers received customer cases, they would upload log files to the data lake stored in Amazon Simple Storage Service (Amazon S3). The original design then suffered from the complexity of multi-step raw data processing.
First, CyberArk’s custom parsing logic running on AWS Fargate would parse these uploaded log files and transform the raw data. During this stage, the system also had to scan for PII and mask sensitive data to protect customer privacy.
Next, a separate process converted the processed data into Parquet format.
Finally, AWS Glue crawlers were required to discover new partitions and update table metadata for processed Parquet files. This dependency became the most complex and time-consuming part of the pipeline. Crawlers ran as asynchronous batch jobs rather than in real time, often introducing delays of minutes to hours before support engineers could query the data.
But the inefficiency went deeper than just architectural complexity. CyberArk supports customers running diverse product environments across multiple vendors. Each vendor and product produces logs in different formats with unique schemas, field names, and structures. Adding support for a new vendor meant days of integration work to understand their log format and build custom parsers.
Figure 1: Legacy log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with AWS Glue Crawler
Beyond ingestion, the investigation process itself was manual and time consuming. Support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. The new architecture addresses these inefficiencies through three key innovations:
Single stage serverless processing: AWS Fargate with PyIceberg directly creates Iceberg tables from raw logs in one pass, removing intermediate processing steps and crawler dependencies entirely.
AI powered dynamic parsing: Amazon Bedrock automatically generates grok patterns for log parsing by analyzing file schemas, transforming what was once a manual, time consuming process into a fully automated workflow.
Autonomous investigation with AI Agents: AI Agents autonomously perform complete root cause analysis by querying log data, analyzing product knowledge bases, identifying event flows, and recommending solutions, transforming hours of manual investigation into minutes of automated intelligence.
The solution: AI-powered automation meets single-stage Iceberg processing
The new system delivers zero touch log processing from upload to query. Support engineers simply upload customer log ZIP files to the system. Here’s where the transformation happens: CyberArk’s custom processing logic still runs on AWS Fargate, but now it uses Amazon Bedrock to intelligently understand the data.
Zero-touch log processing workflow
The system extracts sample log entries from the uploaded log files and sends them to Amazon Bedrock along with context about the log source and table schema from AWS Glue Data Catalog. Amazon Bedrock analyzes the samples, understands the structure, and automatically generates grok patterns optimized for the specific log format.
Grok patterns are structured expressions that define how to extract meaningful fields from unstructured log text. For example, the following grok pattern specifies that a timestamp appears first, followed by a severity level, then a message body %{TIMESTAMP_ISO8601:timestamp} %{LOGLEVEL:severity} %{GREEDYDATA:message}
The system validates these grok patterns against additional samples to verify accuracy before applying them to parse the complete log file. Successfully validated grok patterns are stored in Amazon DynamoDB, creating a repository of known patterns. When the system encounters similar log formats in future uploads, it can retrieve these patterns directly from Amazon DynamoDB, avoiding redundant grok pattern generation. Amazon Bedrock processes log samples in real-time without retaining customer data or using it for model training, maintaining data privacy.
This entire process invokes Claude 3.7 Sonnet model from Amazon Bedrock and is orchestrated by AWS Fargate tasks with retry logic for reliability. The processing uses these AI-generated grok patterns to parse the logs and create or update Iceberg tables using PyIceberg APIs without human intervention.
This automation reduced logs onboarding time from days to minutes, enabling CyberArk to handle diverse customer environments without manual intervention.
Figure 2: Log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with Amazon Bedrock integration to Iceberg table creation
Iceberg simplified and improved CyberArk’s data lake architecture by addressing the two primary bottlenecks in the legacy system: slow schema management and inefficient query performance.
In the legacy architecture, AWS Glue crawlers became a source of operational overhead and latency. Even when triggered on demand, crawlers ran as batch jobs over S3 prefixes to discover partitions and update metadata. As data volumes grew and datasets diversified across vendors and schemas, teams had to manage and operate a growing number of crawler jobs. The resulting delays, often ranging from minutes to hours, slowed data availability and downstream investigation workflows.
Iceberg removes this entire layer of complexity. Iceberg’s intelligent metadata layer automatically tracks table structure, schema changes, and partition information as data is written. When CyberArk’s processing creates or updates Iceberg tables through PyIceberg, the metadata is updated instantly and atomically. There’s no waiting for crawlers jobs to complete, and no risk of stale metadata. The moment data is written, it’s immediately queryable in Amazon Athena.
PyIceberg: Making Iceberg accessible beyond Apache Spark
Working with Iceberg usually involved Apache Spark and the complexity of distributed data processing. PyIceberg changed that by letting CyberArk create and manage Iceberg tables using a simple Python library. CyberArk’s data engineers could write straightforward Python code running on AWS Fargate to create Iceberg tables directly from parsed logs, without spinning up Spark clusters.
This accessibility was essential for CyberArk’s serverless architecture. PyIceberg enabled single stage processing where AWS Fargate tasks could parse logs, apply PII masking, and create Iceberg tables in one pass. The result was simpler code and lower operational overhead.
Metadata-driven query optimization delivers speed
In addition to removing crawlers, Iceberg significantly improved query performance through its intelligent metadata architecture. Iceberg maintains detailed statistics about data files, including min/max values, null counts, and partition information. When support engineers query data in Athena, Iceberg’s metadata layer supports partition pruning and file skipping, making sure queries only read the specific files containing relevant data. For CyberArk’s use case, where tables are partitioned by case ID, this means a query for a specific support case only reads the files for that case, ignoring potentially thousands of irrelevant files. This metadata driven optimization reduced query execution time from minutes to seconds, allowing support engineers to interactively explore data rather than waiting for results.
ACID transactions maintain data consistency
In a multi user support environment where multiple engineers may be analyzing overlapping cases or uploading logs simultaneously, data consistency is essential. Iceberg’s ACID transaction support helps verify that concurrent writes do not corrupt data or create inconsistent states. Each table update is atomic, isolated, and durable, providing the reliability CyberArk needed for production support operations.
Time travel enables historical analysis
Iceberg’s built-in versioning allows support engineers to query historical states of data, essential for understanding how customer issues evolved over time. If an engineer needs to see what the logs looked like when a case was first opened versus after a customer applied a patch, Iceberg’s time travel capabilities make this straightforward. This feature proved essential for complex troubleshooting scenarios where understanding the timeline of events was critical to resolution.
Automated table optimization with AWS Glue
Iceberg tables require periodic maintenance to maintain query performance.
CyberArk enabled AWS Glue automatic table optimization for their Iceberg tables, which handles compaction and expired snapshot cleanup in the background.
For CyberArk’s continuous upload workflow, this automation avoids performance degradation over time. Tables stay optimized without manual intervention from the engineering team.
AI Agents: Autonomous investigation workflow
While the Claude 3.7 Sonnet model from Amazon Bedrock automates grok pattern generation for log ingestion, the more advanced use of Amazon Bedrock comes in the investigation workflow. We use AI agents with Bedrock models to change how support engineers analyze and resolve customer issues.
From manual analysis to AI powered investigation
In the legacy workflow, support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. AI Agents automate this entire investigation process. Support engineers use an internal portal to ask questions in natural language about customer issues, questions like “Show me authentication errors for case 12345 in the last 24 hours”, “What were the most common errors across cases opened this week?” or “Compare the error patterns between case 12345 and case 12346.”
Behind the scenes, the system fires specialized AI Agents that autonomously perform thorough analysis.
How support agents work
Each AI Agent operates as an intelligent investigator with a clear mission: understand what happened, determine why it happened, and recommend how to fix it. When a support engineer asks a question, the agent collects relevant data by querying Athena to retrieve log data from Iceberg tables, filtering for the specific case and time period relevant to the investigation. The agent then accesses CyberArk’s internal knowledge base for the specific product involved, understanding known issues, common error patterns, and documented solutions. The agent then performs the following analysis:
Flow identification: Analyzes the sequence of events in the logs to understand what actually happened during the customer’s issue
Root cause determination: Correlates log events with product knowledge to identify the underlying cause of the problem
Solution recommendations: Suggests specific remediation steps based on the root cause analysis and known resolution patterns
This entire process happens in minutes, delivering advanced analysis that would have taken support engineers hours to perform manually.
For complex cases where a solution is not found, the support agent escalates to another, specialized agent that interacts with service engineers to collect additional inputs and expertise. This human-in-the-loop approach makes sure that even the most challenging cases receive appropriate attention while still benefiting from the automated investigation workflow. The insights gathered from these escalated cases are automatically fed back into CyberArk’s knowledge base, continuously improving the system’s ability to handle similar issues autonomously in the future.
Amazon Bedrock never shares customer data with model providers or uses it to train foundation models, case data and investigation insights remain within CyberArk’s environment.
Concurrent agent execution at scale
When multiple support engineers investigate different cases simultaneously, the solution runs specialized agents concurrently. CyberArk currently uses Claude 3.7 Sonnet as the foundation model for these agents. Each agent works independently on its assigned investigation, operating in parallel without resource contention. This concurrent execution allows the investigation workflow to scale automatically with support volume, handling peak loads without performance degradation.
AI-powered investigation advantage
This AI-powered investigation workflow delivers two key advantages.
Investigations that took hours now complete in minutes, enabling support engineers to resolve up to 4x more cases per day.
The system also creates a continuous learning feedback loop. When cases require manual resolution by engineers, these resolutions are automatically recorded and fed back into the knowledge base. Future investigations benefit from this accumulated expertise, with agents applying lessons learned from previous manual resolutions to similar cases. Amazon Bedrock doesn’t use customer data to train foundation models. Case data and investigation insights remain within CyberArk’s environment. This automated feedback mechanism means the investigation workflow becomes more effective over time, continuously improving resolution accuracy and speed.
Figure 3: Investigation workflow diagram showing natural language query through AI Agents to Athena queries and knowledge base analysis
Scaling without proportional engineering growth
The business impact of this AI automation is significant. CyberArk can expand its vendor coverage and product portfolio without adding data engineering headcount. The same system that handles today’s log types will automatically handle tomorrow’s additions, whether that’s ten new formats or thousands, significantly reducing time to market for new product and vendor integrations.
The results: Significant improvements in resolution time and productivity
The transformation delivered measurable improvements across every key metric.
Resolution time: CyberArk achieved up to 95% reduction in time from case assignment to resolution. Simple cases that used to take 4 to 6 hours now take just 15 to 30 minutes. Complex cases that previously took up to 15 days are now completed in 2 to 4 hours.
Engineer productivity: Support engineers now handle 8 to 12 cases per day, compared to just 2 to 3 cases before. This means each engineer is helping up to 4x more customers.
Data availability: Logs are queryable within minutes of upload instead of waiting hours or days. Support engineers can start investigating issues almost immediately after receiving customer data.
Operational efficiency: The system requires zero manual intervention for new log formats or schema changes. Cases that used to require days of data engineering work now happen automatically.
Cost optimization: The serverless architecture alleviated idle infrastructure costs while scaling automatically with demand. CyberArk only pays for what they use, when they use it.
Customer satisfaction: Faster resolution times and proactive issue identification significantly improved the customer experience. Problems get solved in hours instead of days, and customers spend less time waiting for answers.
What’s next?
While AWS continues to innovate across both data lake management and agentic AI infrastructure, the following capabilities align well with CyberArk’s architecture and may offer additional operational benefits as the system scale.
Agent infrastructure maturity
As the agent-based architecture scales to handle thousands of concurrent investigations, CyberArk is transitioning to Amazon Bedrock AgentCore for future agent deployments. AgentCore provides a managed runtime for production AI agents with enhanced observability through AWS X-Ray integration, intelligent memory for context retention across sessions, and streamlined operational workflows. While the current AI Agents implementation delivers the performance and reliability CyberArk needs today, AgentCore represents a natural evolution path as operational requirements grow, offering framework-agnostic deployment, automatic scaling, and comprehensive monitoring capabilities without infrastructure management overhead.
Amazon S3 Tables
CyberArk’s current architecture uses Iceberg tables stored in Amazon S3 buckets. Amazon S3 Tables offers fully managed Iceberg tables with built-in optimization.
As CyberArk continue to scale with hundreds of Iceberg tables and rapid data growth, CyberArk is exploring a migration to Amazon S3 Tables to further reduce operational overhead.
S3 Tables remove the need to set up and monitor AWS Glue maintenance jobs. It automatically performs maintenance to enhance the performance of Iceberg tables, including unreferenced file removal, file compaction, and snapshot management. Additionally, S3 Tables provides Intelligent-Tiering that automatically moves data between storage classes based on access patterns, optimizing storage costs without manual intervention.
Because S3 Tables uses Iceberg open table format, migration would not require changes to existing Athena queries and PyIceberg code. This flexibility allows CyberArk to evaluate and adopt S3 Tables when the operational and cost benefits align with their business needs.
Conclusion
CyberArk’s transformation demonstrates how combining modern data lake architecture with AI automation can significantly change operational economics. By combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock, CyberArk transformed case resolution from days to minutes while enabling support operations to scale automatically with business growth. Support engineers now spend their time solving customer problems instead of wrangling data, customers receive faster resolutions, and the system scales automatically with the business.
I joined AWS in 2021, and since then I’ve watched the Amazon Elastic Compute Cloud (Amazon EC2) instance family grow at a pace that still surprises me. From AWS Graviton-powered instances to specialized accelerated computing options, it feels like every few months there’s a new instance type landing that pushes performance boundaries further. As of February 2026, AWS offers over 1,160 Amazon EC2 instance types, and that number keeps climbing.
This week’s opening news is a good example: The general availability of Amazon EC2 M8azn instances. These are general purpose, high-frequency, high-network instances powered by fifth generation AMD EPYC processors, offering the highest maximum CPU frequency in the cloud at 5 GHz. Compared to the previous generation M5zn instances, M8azn instances deliver up to 2x compute performance, 4.3x higher memory bandwidth, and a 10x larger L3 cache. They also provide up to 2x networking throughput and up to 3x Amazon Elastic Block Store (Amazon EBS) throughput compared with M5zn.
Built on the AWS Nitro System using sixth generation Nitro Cards, M8azn instances target workloads such as real-time financial analytics, high-performance computing, high-frequency trading, CI/CD pipelines, gaming, and simulation modeling across automotive, aerospace, energy, and telecommunications. The instances feature a 4:1 ratio of memory to vCPU and are available in 9 sizes ranging from 2 to 96 vCPUs with up to 384 GiB of memory, including two bare metal variants. For more information visit the Amazon EC2 M8azn instance page.
Last week’s launches Here are some of the other announcements from last week:
Amazon Bedrock adds support for six fully managed open weights models – Amazon Bedrock now supports DeepSeek V3.2, MiniMax M2.1, GLM 4.7, GLM 4.7 Flash, Kimi K2.5, and Qwen3 Coder Next. These models span frontier reasoning and agentic coding workloads. DeepSeek V3.2 and Kimi K2.5 target reasoning and agentic intelligence, GLM 4.7 and MiniMax M2.1 support autonomous coding with large output windows, and Qwen3 Coder Next and GLM 4.7 Flash provide cost-efficient alternatives for production deployment. These models are powered by Project Mantle and provide out-of-the-box compatibility with OpenAI API specifications. With the launch, you can also use new open weight models–DeepSeek v3.2 , MiniMax 2.1, and Qwen3 Coder Next in Kiro, a spec-driven AI development tool.
Amazon Bedrock expands support for AWS PrivateLink – Amazon Bedrock now supports AWS PrivateLink for the bedrock-mantle endpoint, in addition to existing support for the bedrock-runtime endpoint. The bedrock-mantle endpoint is powered by Project Mantle, a distributed inference engine for large-scale machine learning model serving on Amazon Bedrock. Project Mantle provides serverless inference with quality of service controls, higher default customer quotas with automated capacity management, and out-of-the-box compatibility with OpenAI API specifications. AWS PrivateLink support for OpenAI API-compatible endpoints is available in 14 AWS Regions. To get started, visit the Amazon Bedrock console or the OpenAI API compatibility documentation.
Amazon EKS Auto Mode announces enhanced logging for managed Kubernetes capabilities – You can now configure log delivery sources using Amazon CloudWatch Vended Logs in Amazon EKS Auto Mode. This helps you collect logs from Auto Mode’s managed Kubernetes capabilities for compute autoscaling, block storage, load balancing, and pod networking. Each Auto Mode capability can be configured as a CloudWatch Vended Logs delivery source with built-in AWS authentication and authorization at a reduced price compared to standard CloudWatch Logs. You can deliver logs to CloudWatch Logs, Amazon S3, or Amazon Data Firehose destinations. This feature is available in all Regions where EKS Auto Mode is available.
Amazon OpenSearch Serverless now supports Collection Groups – You can use new Collection Groups to share OpenSearch Compute Units (OCUs) across collections with different AWS Key Management Service (AWS KMS) keys. Collection Groups reduce overall OCU costs through a shared compute model while maintaining collection-level security and access controls. They also introduce the ability to specify minimum OCU allocations alongside maximum OCU limits, providing guaranteed baseline capacity at startup for latency-sensitive applications. Collection Groups are available in all Regions where Amazon OpenSearch Serverless is currently available.
Amazon RDS now supports backup configuration when restoring snapshots – You can view and modify the backup retention period and preferred backup window before and during snapshot restore operations. Previously, restored database instances and clusters inherited backup parameter values from snapshot metadata and could only be modified after restore was complete. You can now view backup settings as part of automated backups and snapshots, and specify or modify these values when restoring, eliminating the need for post-restoration modifications. This is available for all Amazon RDS database engines (MySQL, PostgreSQL, MariaDB, Oracle, SQL Server, and Db2) and Amazon Aurora (MySQL-Compatible and PostgreSQL-Compatible editions) in all AWS commercial Regions and AWS GovCloud (US) Regions at no additional cost.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits – Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
AWS AI and Data Conference 2026 – A free, single-day in-person event on March 12 at the Lyrath Convention Centre in Ireland. The conference covers designing, training, and deploying agents with Amazon Bedrock, Amazon SageMaker, and QuickSight, integrating them with AWS data services, and applying governance practices to operate them at scale. The agenda includes strategic guidance and hands-on labs for architects, developers, and business leaders.
AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders, featuring technical discussions, workshops, and hands-on labs. Upcoming events include Ahmedabad (February 28), Slovakia (March 11), and Pune (March 21).
Here are the notable launches and updates from last week that can help you build, scale, and innovate on AWS.
Last week’s launches Here are the launches that got my attention this week.
Let’s start with news related to compute and networking infrastructure:
Introducing Amazon EC2 C8id, M8id, and R8id instances: These new Amazon EC2 C8id, M8id, and R8id instances are powered by custom Intel Xeon 6 processors. These instances offer up to 43% higher performance and 3.3x more memory bandwidth compared to previous generation instances.
AWS Network Firewall announces new price reductions: The service has added the hourly and data processing discounts on NAT Gateways that are service-chained with Network Firewall secondary endpoints. Additionally, AWS Network Firewall has removed additional data processing charges for Advanced Inspection, which enables Transport Layer Security (TLS) inspection of encrypted network traffic.
Amazon ECS adds Network Load Balancer support for Linear and Canary deployments: Applications that commonly use NLB, such as those requiring TCP/UDP-based connections, low latency, long-lived connections, or static IP addresses, can take advantage of managed, incremental traffic shifting natively from ECS when rolling out updates.
AWS Config now supports 30 new resource types: These range across key services including Amazon EKS, Amazon Q, and AWS IoT. This expansion provides greater coverage over your AWS environment, enabling you to more effectively discover, assess, audit, and remediate an even broader range of resources.
Amazon DynamoDB global tables now support replication across multiple AWS accounts: DynamoDB global tables are a fully managed, serverless, multi-Region, and multi-active database. With this new capability, you can replicate tables across AWS accounts and Regions to improve resiliency, isolate workloads at the account level, and apply distinct security and governance controls.
Amazon RDS now provides an enhanced console experience to connect to a database: The new console experience provides ready-made code snippets for Java, Python, Node.js, and other programming languages as well as tools like the psql command line utility. These code snippets are automatically adjusted based on your database’s authentication settings. For example, if your cluster uses IAM authentication, the generated code snippets will use token-based authentication to connect to the database. The console experience also includes integrated CloudShell access, offering the ability to connect to your databases directly from within the RDS console.
Then, I noticed three news items related to security and how you authenticate on AWS:
AWS Builder ID now supports Sign in with Apple: AWS Builder ID, your profile for accessing AWS applications including AWS Builder Center, AWS Training and Certification, AWS re:Post, AWS Startups, and Kiro, now supports sign-in with Apple as a social login provider. This expansion of sign-in options builds on the existing sign-in with Google capability, providing Apple users with a streamlined way to access AWS resources without managing separate credentials on AWS.
AWS STS now supports validation of select identity provider specific claims from Google, GitHub, CircleCI and OCI: You can reference these custom claims as condition keys in IAM role trust policies and resource control policies, expanding your ability to implement fine-grained access control for federated identities and help you establish your data perimeters. This enhancement builds upon IAM’s existing OIDC federation capabilities, which allow you to grant temporary AWS credentials to users authenticated through external OIDC-compatible identity providers.
Amazon CloudFront announces mutual TLS support for origins: Now with origin mTLS support, you can implement a standardized, certificate-based authentication approach that eliminates operational burden. This enables organizations to enforce strict authentication for their proprietary content, ensuring that only verified CloudFront distributions can establish connections to backend infrastructure ranging from AWS origins and on-premises servers to third-party cloud providers and external CDNs.
Finally, there is not a single week without news around AI :
Claude Opus 4.6 now available in Amazon Bedrock: Opus 4.6 is Anthropic’s most intelligent model to date and a premier model for coding, enterprise agents, and professional work. Claude Opus 4.6 brings advanced capabilities to Amazon Bedrock customers, including industry-leading performance for agentic tasks, complex coding projects, and enterprise-grade workflows that require deep reasoning and reliability.
Structured outputs now available in Amazon Bedrock: Amazon Bedrock now supports structured outputs, a capability that provides consistent, machine-readable responses from foundation models that adhere to your defined JSON schemas. Instead of prompting for valid JSON and adding extra checks in your application, you can specify the format you want and receive responses that match it—making production workflows more predictable and resilient.
Upcoming AWS events Check your calendars so that you can sign up for this upcoming event:
AWS Community Day Romania (April 23–24, 2026): This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.
If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.
Educational technology (EdTech) providers face the challenge of maintaining seamless, personalized communication and presenting the right recommendations to their diverse stakeholders. This post explores how combining Amazon Web Services (AWS) End User Messaging and WhatsApp Business API with the advanced AI capabilities of Amazon Bedrock can transform educational engagement.
In this post, we explore use cases that are reshaping the EdTech industry. We discover how application automation can streamline admissions and enrollment processes, making them more efficient and user-friendly. We demonstrate how instant student engagement can be achieved through AI-powered, personalized interactions that keep learners motivated and connected. We showcase how real-time course feedback mechanisms can help educators adapt and improve their teaching methods. We also examine how student support can be automated using intelligent assistants that provide continuous, all-day assistance while maintaining a personal touch.
We show you how to build an AI-powered course recommendation system. We explain how to set up WhatsApp Business API integration with Amazon Bedrock, implement smart search capabilities for course matching, and create a scalable serverless architecture. You’ll learn how to build meaningful analytics dashboards to track engagement and learn best practices for handling errors and maintaining system reliability. Whether you’re an EdTech professional or a cloud architect, this guide gives you practical insights into combining conversational AI with educational services.
Use cases
An AI-powered personalized learning pathway generator that automatically recommends customized content based on individual student performance metrics and learning requirements
Course improvement suggestions and real-time course feedback
A smart communication orchestrator that delivers role-specific, automated notifications and updates across multiple channels to enhance student and parent engagement
An early warning system using predictive analytics to identify at-risk students through real-time monitoring of engagement metrics and performance indicators
Student support automation with always available AI assistant support, FAQ handling, escalation management, and multilingual support
Prerequisites
An AWS account
AWS End User Messaging set up with WhatsApp channel enabled
A pre-existing WhatsApp Business account
Amazon Bedrock setup must be completed with preferred model
With this solution, users can discover and order educational courses through WhatsApp conversations. Instead of navigating complex websites, the user can send a WhatsApp message saying, “I want to learn Python programming.” They’ll receive personalized course recommendations instantly. The architecture processes WhatsApp messages through AWS End User Messaging, uses Amazon Bedrock for AI-powered conversations, performs semantic search with Amazon OpenSearch Serverless, and captures analytics for business insights. (For step-by-step implementation and rollback guidelines, see the sample course recommendation system.) The following architectural diagram illustrates a modern AI-powered course recommendation system that uses multiple AWS services.
Figure 1: AI-powered course recommendation system
Message processing
When users send WhatsApp messages, AWS End User Messaging captures them and publishes events to an Amazon Simple Notification Service (Amazon SNS) topic. This creates a decoupled architecture where multiple services can process the same message events independently. AWS Lambda functions subscribe to these events, facilitating reliable message processing during high-traffic periods. The decoupled design provides several advantages:
If one component fails, others continue operating
You can add new message processors without affecting existing ones
The system automatically scales based on message volume without manual intervention
AI conversation engine
Amazon Bedrock with Claude 3 Haiku powers natural language understanding. It is configured specifically for WhatsApp with instructions for short paragraphs, relevant emoji, and mobile-optimized responses.
AI agents
The agent maintains conversation context and handles structured actions such as course search, detail retrieval, and booking through defined functions. The following workflow is the agent action flow and sample code:
Can switch between actions based on user responses
Handles complex queries by combining multiple actions
Sample code
The following is sample code to create a Bedrock agent using AWS CDK:
    agent = bedrock.CfnAgent(foundation_model="anthropic.claude-3-haiku-20240307-v1:0",
     instruction="""
     Format for WhatsApp: short paragraphs,
        focus on technical courses only
       """,
      action_groups=[# Functions for search, details, booking]
)
Semantic search
Traditional keyword search can miss the user’s intent. The application uses Amazon Titan Embeddings in Amazon Bedrock to convert courses and queries into vectors, enabling semantic understanding. When users ask for “cloud computing courses,” the system can understand related terms such as “AWS” and “serverless” without exact matches. Amazon OpenSearch Serverless handles vector similarity matching combined with traditional filters for course price, level, and duration.
Analytics pipeline
Every WhatsApp message interaction generates business intelligence. Messages are stored in Amazon Simple Storage Service (Amazon S3) with date partitioning, catalogued through AWS Glue, and made queryable using Amazon Athena. Teams can analyze user behavior, popular topics, and conversion rates through Quick Sight dashboards. The following dashboard shows example widgets displaying pie-chart breakdown of message delivery status and count of messages per day.
Figure 2: Amazon Quick Sight dashboard
As shown in the following dashboard, Amazon Q in QuickSight enables you to explore and analyze your data using conversational AI capabilities.
Such highly scalable and distributed solutions require robust error handling. The application has exponential backoff and retries for API calls, meaning the system can gracefully handle rate limits and temporary service unavailability.
The following is sample code for error handling and resilience:
With the global EdTech market expected to reach $165 billion by 2026, educators and institutions are seeking solutions to prevent student dropouts, improve learning outcomes, and maintain their competitive advantage. Poor personalization can lead to decreased student engagement, lower course completion rates, and ultimately revenue loss.
Implementing AI-driven personalization and communication systems means institutions can significantly improve student retention rates, boost learning outcomes, and create a more engaging educational experience, which directly impacts their bottom line and reputation in an increasingly competitive educational landscape. This solution could transform educational delivery through intelligent personalization and operational excellence. A serverless architecture can help educational institutions focus on content quality rather than infrastructure management while potentially maintaining rapid response times for course searches. The system’s analytics capabilities could offer insights into student behavior and course preferences, helping shape future curriculum development.
With mobile optimization, institutions can better serve the growing population of digital-first learners. The combination of automated scaling and pay-per-use pricing could create opportunities for cost optimization, and real-time dashboards can be used to facilitate data-informed decision-making. Such improvements in user experience and operational efficiency could lead to enhanced student engagement and institutional growth in the evolving education environment.
Sample conversation
The following video shows how a user can interact with the generative AI-powered course recommendation system and receive course recommendations.
Future enhancements
We’re expanding to more messaging platforms, adding voice integration through Amazon Connect, and implementing predictive analytics for personalized recommendations. The serverless architecture makes these additions straightforward without infrastructure changes. Future scenarios could involve:
Educator and student support – This solution can be enhanced for student and educator experiences. For educators, it can automate administrative tasks. For students, it can create personalized engagement campaigns, a communication approach that could be significantly more effective than traditional methods.
Digital admission process flow – The solution integrates AWS Bedrock AI with WhatsApp Business API to streamline digital admissions. It can enable instant document verification, guide secure payments, and provide automated updates, all within the AWS End User Messaging WhatsApp channel. This AI-powered system could transform the complex admission process into an efficient, chat-based experience, benefiting both institutions and applicants.
Parental support and study material management – The system could intelligently distribute learning resources based on student needs, send automated schedule updates, and provide personalized progress reports to parents through WhatsApp. Parents could receive AI-curated study materials and real-time updates about their child’s academic performance, homework assignments, and upcoming assessments through familiar chat interactions. This integration could transform traditional parent-teacher communication into an efficient, automated system while providing timely access to relevant educational resources.
Conclusion
The WhatsApp course recommender agent demonstrates how modern AWS services can create sophisticated, AI-powered conversational experiences that scale automatically and provide rich business insights. The serverless architecture provides cost-effectiveness while maintaining enterprise-grade reliability. Key architectural principles that make this solution successful include event-driven design for scalability, AI integration for natural interactions, semantic search for superior user experience, customizable analytics for business intelligence, and infrastructure as code (IaC) for reliable deployments.
For organizations considering similar implementations, we recommend focusing on user experience optimization, robust error handling, comprehensive monitoring, and gradual feature rollout. The conversational AI environment is rapidly evolving, and solutions that prioritize user experience while maintaining technical excellence can drive the most business value. This implementation can serve as a reference architecture for building production-ready conversational AI systems on AWS, demonstrating patterns that can apply across industries and use cases.
Over the past week, we passed Laba festival, a traditional marker in the Chinese calendar that signals the final stretch leading up to the Lunar New Year. For many in China, it’s a moment associated with reflection and preparation, wrapping up what the year has carried, and turning attention toward what lies ahead.
Looking forward, next week also brings Lichun, the beginning of spring and the first of the 24 solar terms. In Chinese tradition, spring is often seen as the season when growth begins and new cycles take shape. There’s a common saying that “a year’s plans begin in spring,” capturing the idea that this is a time to set one’s direction and start fresh.
Last week’s launches Here are the launches that got my attention this week:
Amazon Bedrock enhances support for agent workflows with server-side tools and extended prompt caching – Amazon Bedrock introduced two updates that improve how developers build and operate AI agents. The Responses API now supports server-side tool use, so agents can perform actions such as web search, code execution, and database updates within AWS security boundaries. Bedrock also adds a 1-hour time-to-live (TTL) option for prompt caching, which helps improve performance and reduce the cost for long-running, multi-turn agent workflows. Server-side tools are available with OpenAI GPT OSS 20B and 120B models, and the 1-hour prompt caching TTL is generally available for select Claude models by Anthropic in Amazon Bedrock.
Amazon SageMaker Unified Studio adds private VPC connectivity with AWS PrivateLink – Amazon SageMaker Unified Studio now supports AWS PrivateLink, providing private connectivity between your VPC and SageMaker Unified Studio without routing customer data over the public internet. With SageMaker service endpoints onboarded into a VPC, data traffic remains within the AWS network and is governed by IAM policies, supporting stricter security and compliance requirements.
Amazon S3 adds support for changing object encryption without data movement – Amazon S3 now supports changing the server-side encryption type of existing encrypted objects without moving or re-uploading data. Using the UpdateObjectEncryption API, you can switch from SSE-S3 to SSE-KMS, rotate customer -managed AWS Key Management Service (AWS KMS) keys, or standardize encryption across buckets at scale with S3 Batch Operations while preserving object properties and lifecycle eligibility.
Amazon Keyspaces introduces table pre-warming for predictable high-throughput workloads – Amazon Keyspaces (for Apache Cassandra) now supports table pre-warming, which helps you proactively set warm throughput levels so tables can handle high read and write traffic instantly without cold-start delays. Pre-warming helps reduce throttling during sudden traffic spikes, such as product launches or sales events, and works with both on-demand and provisioned capacity modes, including multi-Region tables. The feature supports consistent, low-latency performance while giving you more control over throughput readiness.
Additional updates Here are some additional projects, blog posts, and news items that I found interesting:
Building zero-trust access across multi-account AWS environments with AWS Verified Access – This post walks through how to implement AWS Verified Access in a centralized, shared-services architecture. It shows how to integrate with AWS IAM Identity Center and AWS Resource Access Manager (AWS RAM) to apply zero trust access controls at the application layer and reduce operational overhead across multi-account AWS environments.
Amazon EventBridge increases event payload size to 1 MB – Amazon EventBridge now supports event payloads up to 1 MB, an increase from the previous 256 KB limit. This update helps event-driven architectures carry richer context in a single event, including complex JSON structures, telemetry data, and machine learning (ML) or generative AI outputs, without splitting payloads or relying on external storage.
AWS MCP Server adds deployment agent SOPs (preview) – AWS introduced deployment standard operating procedures (SOPs) that AI agents can deploy web applications to AWS from a single natural language prompt in MCP -compatible integrated development environments (IDEs) and command line interfaces (CLIs) such as Kiro, Cursor, and Claude Code. The agent generates AWS Cloud Development Kit (AWS CDK) infrastructure, deploys AWS CloudFormation stacks, and sets up continuous integration and continuous delivery (CI/CD) workflows following AWS best practices. The preview supports frameworks including React, Vue.js, Angular, and Next.js.
AWS Network Firewall adds generation AI traffic visibility with web category filtering – AWS Network Firewall now provides visibility into generative AI application traffic through predefined web categories. You can use these categories directly in firewall rules to govern access to generative AI tools and other web services. When combined with TLS inspection, category-based filtering can be applied at the full URL level.
AWS Lambda adds enhanced observability for Kafka event source mappings – AWS Lambda introduced enhanced observability for Kafka event source mappings, providing Amazon CloudWatch Logs and metrics to monitor event polling configuration, scaling behavior, and event processing state. The update improves visibility into Kafka-based Lambda workloads, helping teams diagnose configuration issues, permission errors, and function failures more efficiently. The capability supports both Amazon Managed Streaming for Apache Kafka (Amazon MSK) and self-managed Apache Kafka event sources.
AWS CloudFormation 2025 year in review – This year-in-review post highlights CloudFormation updates delivered throughout 2025, with a focus on early validation, safer deployments, and improved developer workflows. It covers enhancements such as improved troubleshooting, drift-aware change sets, stack refactoring, StackSets updates, and new -IDE and AI -assisted tooling, including the CloudFormation language server and the Infrastructure as Code (IaC) MCP server.
Upcoming AWS events Check your calendars so that you can sign up for this upcoming event:
AWS Community Day Romania (April 23–24, 2026) – This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.
If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.
Stay current with the latest serverless innovations that can transform your applications. In this 31st quarterly recap, discover the most impactful AWS serverless launches, features, and resources from Q4 2025 that you might have missed.
In case you missed our last ICYMI, check out what happened in Q3 2025.
2025 Q4 calendar
Serverless at re:Invent 2025
This post covers the biggest serverless announcements from re:Invent 2025, highlighting key feature updates that can improve your applications, and shares valuable resources to keep you informed.
AWS re:Invent 2025 had more than 60,000 in-person attendees and more than 2 million online viewers for the keynotes. The event featured 3,500 sessions from 3,000 speakers, which included information on 530 AWS service and feature announcements.
Keynote Igniting the serverless movement
The serverless content consisted of two tracks: Containers and Serverless (CNS) and Application Integration (API). These tracks included 150 unique sessions watched in-person by more than 16,000 attendees. There were developer-focused experiences including a Road to re:Invent Hackathon, AWS Builder Loft, and Builders Arena. Serverlesspresso, the coffee shop powered by serverless technology, operated in two locations during the event: the Expo Hall and the certification lounge.
Managing state across multi-step serverless workflows has traditionally required complex external orchestration tools. AWS Lambdadurable functions expand how developers can use Lambda. You can now build reliable multi-step applications and AI workflows directly within Lambda.
AWS Lambda durable functions code
Durable functions automatically checkpoint progress by saving the current state and completed steps at key points during execution. This allows them to suspend execution for up to one year during long-running tasks and recover from failures by resuming from the last checkpoint rather than restarting from the beginning, all without requiring additional infrastructure management.
Developers can now build in Python or TypeScript, wrap calls in steps with automatic retries and checkpointing. You can use waits to suspend execution for minutes, hours, or even up to a year without paying for idle compute. Durable functions use a replay mechanism to maintain state and handle failures gracefully. The replay mechanism works by re-executing your function code from checkpoints when recovering from failures, ensuring state consistency without data loss. This also means you don’t need complex external orchestration tools for many use cases. This can be helpful for AI workflows and multi-step applications where you need reliable state management without managing external infrastructure.
Lambda now offers Lambda Managed Instances, a new compute option that combines Amazon EC2 flexibility with fully managed infrastructure. AWS automatically handles instance provisioning, scaling, and maintenance while allowing access to the full range of EC2 capabilities, including Graviton4, network-optimized instances, and other specialized compute options.
AWS Lambda Managed Instances configuration
Your functions run on dedicated EC2 capacity from your account, in your own Amazon Virtual Private Cloud (Amazon VPC). AWS still manages the operational overhead, including OS patching, load balancing, and auto-scaling. This gives you access to specialized hardware options while maintaining the serverless operational model. You can further improve costs by using EC2 pricing models, including Compute Savings Plans and Reserved Instances for Lambda workloads. Each instance can handle multiple concurrent requests, making this particularly valuable for high-volume, steady-state workloads where predictable pricing and specific hardware requirements matter.
Multi-tenant SaaS applications face challenges like data leakage between tenants and noisy neighbor effects where one tenant’s workload impacts others. They also struggle with implementing custom isolation mechanisms. Tenant isolation mode addresses these by processing function invocations in separate execution environments for each tenant. This manages tenant-level compute environment isolation automatically.
AWS Lambda tenant isolation
Lambda adds Provisioned Mode for Amazon SQS event-source mappings, providing predictable performance and reduced cold starts for high-throughput SQS processing workloads.
Lambda functions now support IPv6 networking, so you don’t need NAT Gateways when accessing the internet or other AWS services from VPC-connected functions.
Lambda internet connectivity through a NAT Gateway (IPv4) and Lambda internet connectivity through an egress-only internet gateway (IPv6).
Lambda Rust support is now generally available, moving from experimental status. This is backed by AWS Support and the Lambda availability SLA.
Lambda has expanded its runtime support by adding Python 3.14, Node.js 24, and Java 25 as both managed runtimes and container base images, providing access to the latest language features and ensuring long-term support.
Amazon ECS
Amazon Elastic Container Service (Amazon ECS) Express Mode streamlines the deployment and management of containerized applications by automating the infrastructure setup that traditionally slows down developers.
Amazon ECS Express Mode deployment
This means you can focus on building applications while deploying with confidence using AWS best practices. Express Mode lets you deploy production-ready containerized web applications and APIs with a single command. This automatically handles domains, networking, load balancing, AWS Identity and Access Management (IAM) roles, and auto-scaling through simplified APIs. When your applications evolve and require advanced features, you can seamlessly configure and access the full capabilities of the resources, including Amazon ECS. Learn more from the launch blog post.
Amazon ECS announced a public preview of a fully managed MCP server, enabling AI-powered experiences for development and operations. The Model Context Protocol (MCP) server provides enterprise-grade capabilities like automatic updates and patching, centralized security through AWS IAM integration, comprehensive audit logging via AWS CloudTrail, and the proven scalability, reliability, and support of AWS.
Amazon Elastic Container Registry (ECR)managed container image signing enhances your security posture and eliminates the operational overhead of setting up signing. Container image signing allows you to verify that images are from trusted sources. ECR automatically signs images as they are pushed using the identity of the entity pushing the image. Signing operations are logged through CloudTrail for full auditability.
Amazon API Gateway
Amazon API Gateway allows you to improve the responsiveness of your REST APIs by progressively streaming response payloads back to the client. With this new capability, you can use streamed responses to enhance user experience when building LLM-driven applications (such as AI agents and chatbots), improve time-to-first-byte (TTFB) performance for web and mobile applications, stream large files, and perform long-running operations while reporting incremental progress using protocols such as server-sent events (SSE).
Amazon API Gateway streaming
API Gateway introduces private integration with Application Load Balancers (ALBs). You can use this to expose your VPC-based applications securely through REST APIs without exposing your ALBs to the public internet.
You can also now configure enhanced TLS security policies on API endpoints and custom domain names, providing you with greater control over the security posture of your APIs.
Amazon EventBridge
Amazon EventBridge introduced an enhanced visual rule builder that helps developers discover and subscribe to events from custom applications and over 200 AWS services. The console-based interface integrates the EventBridge schema registry with a comprehensive event catalog and intuitive drag-and-drop canvas that simplifies building event-driven applications. Developers can browse and search through events with readily available sample payloads and schemas without having to hunt through individual service documentation. The schema-aware visual builder guides developers through creating event filter patterns and rules, reducing syntax errors and accelerating development time.
AWS Step Functions allows for enhanced local testing through the TestState API, providing programmatic access to comprehensive testing capabilities without deploying to AWS. This helps you build automated test suites that validate your workflow definitions locally on your development machines. Test error handling patterns, data transformations, and mock service integrations using your preferred testing frameworks.
There is also a new metrics dashboard, giving you visibility into your workflow operations at both the account and state machine levels.
Other announcements
Savings Plans flexible pricing model extends to AWS managed database services with the launch of Database Savings Plans. This helps reduce database costs by up to 35% when committing to a consistent amount of usage ($/hour) over a 1-year term. Savings automatically apply each hour to eligible usage across supported database services, and additional usage beyond the commitment is billed at on-demand rates.
Amazon DynamoDB now supports multi-attribute composite keys in global secondary indexes. You no longer need to concatenate values into synthetic keys manually, which sometimes results in the need to backfill data before adding new indexes. Instead, you can create primary keys using up to eight existing attributes, making it easier to model diverse access patterns and adapt to new query requirements.
The Strands Agents SDK is an open source framework that takes a model-driven approach to building and running AI agents in just a few lines of code. TypeScript support is now available in preview so you can choose between Python and TypeScript for building Strands Agents.
Amazon S3 Vectors became generally available. S3 Vectors delivers purpose-built, cost-optimized vector storage for AI agents, inference, Retrieval Augmented Generation (RAG), and semantic search at billion-vector scale.
Join our livestream every Tuesday at 11 AM PT for live discussions, Q&A sessions, and deep dives into serverless technologies. Episodes are available on-demand at serverlessland.com/office-hours.
The Serverless landing page has overall information about building serverless applications. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.
You can also follow the Serverless Developer Advocacy team to see the latest news, follow conversations, and interact with the team.
And finally, visit Serverless Land for all your serverless needs.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
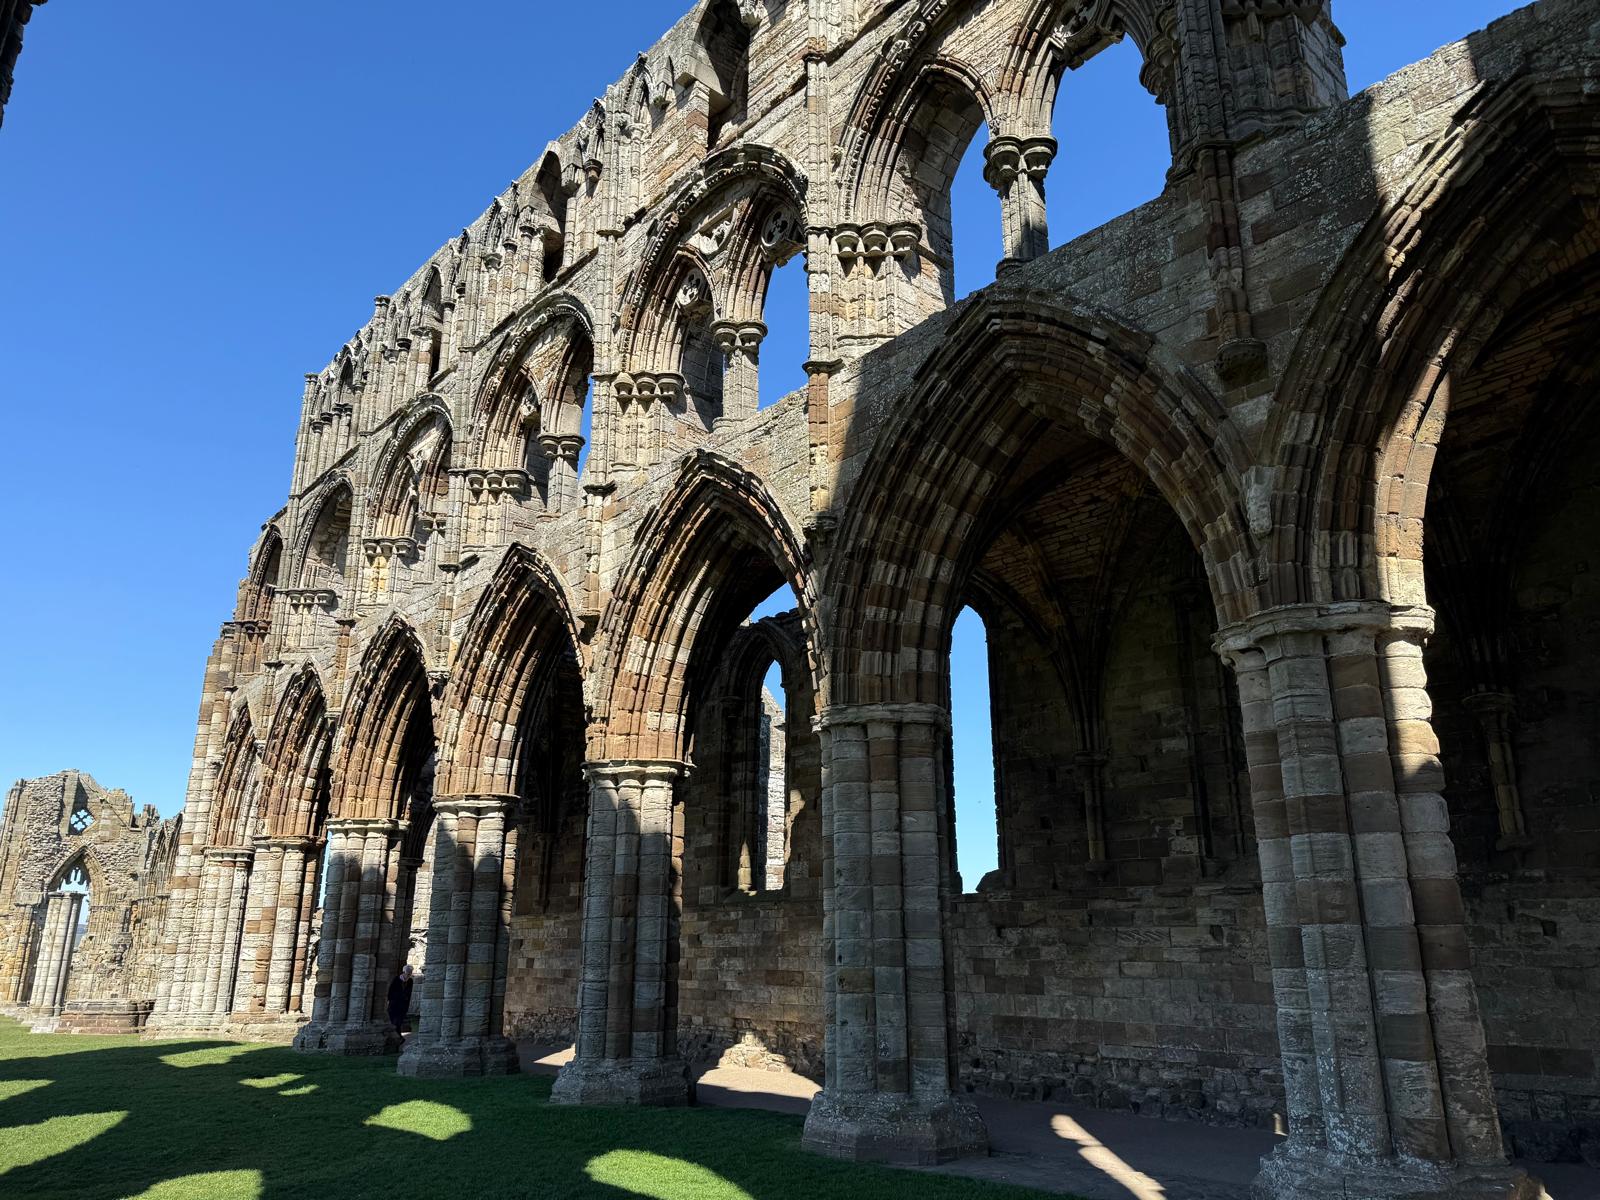
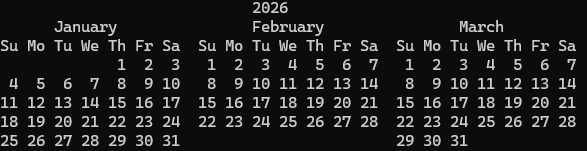
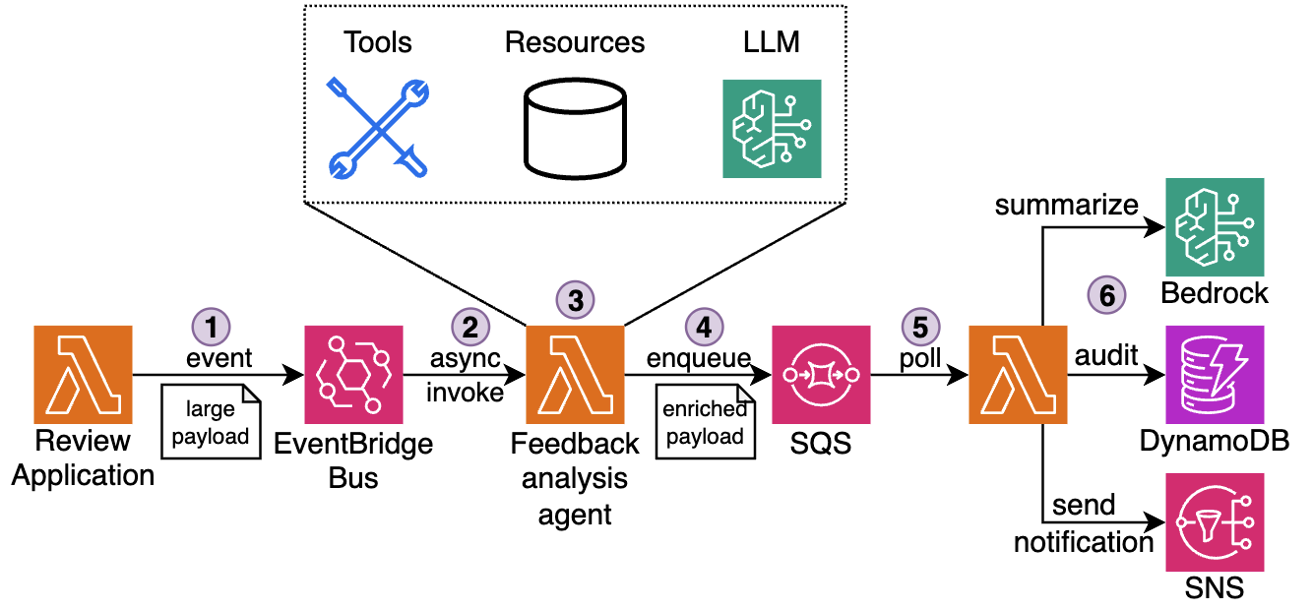
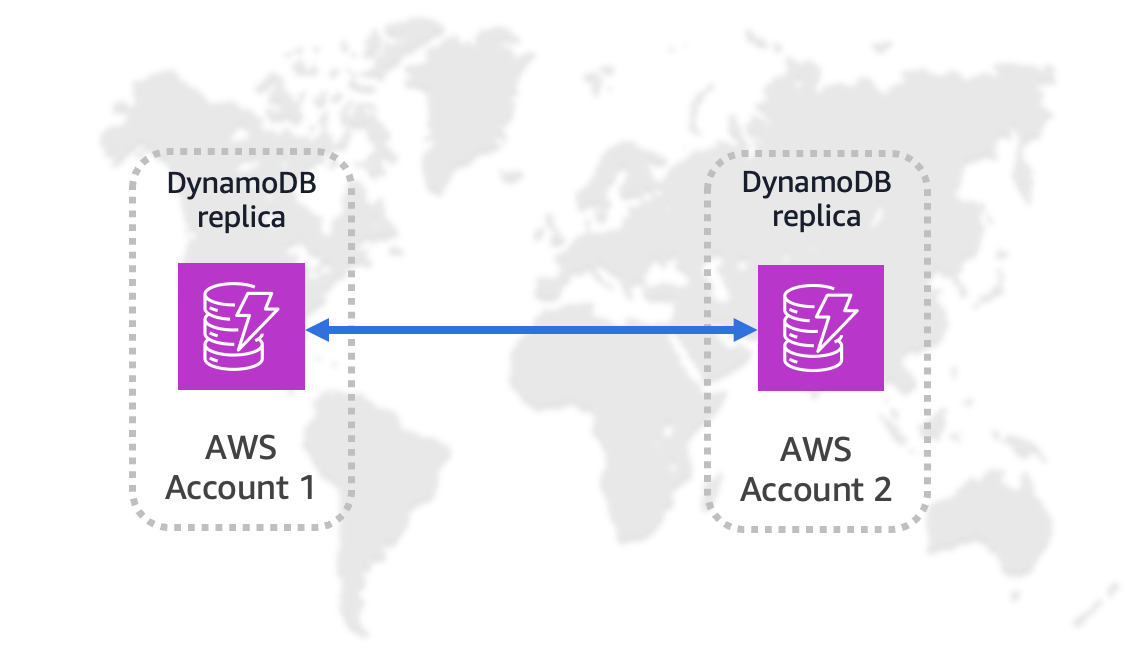
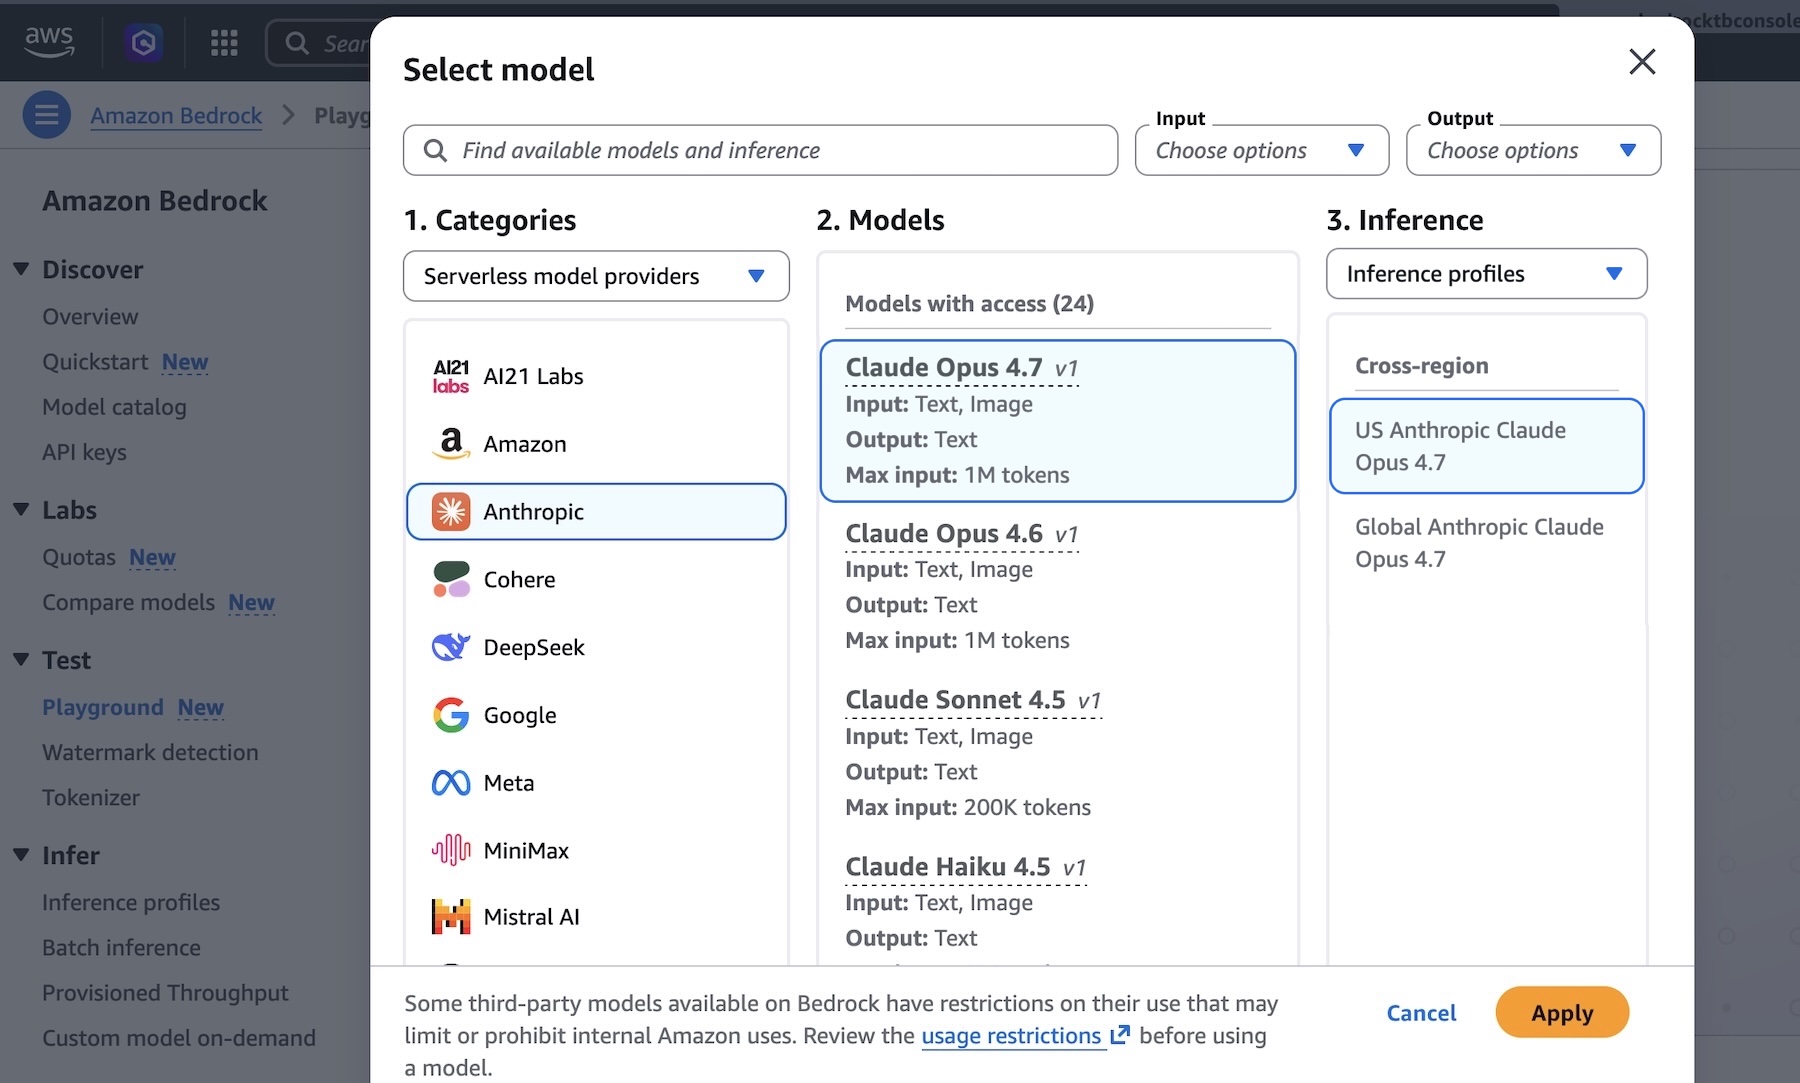
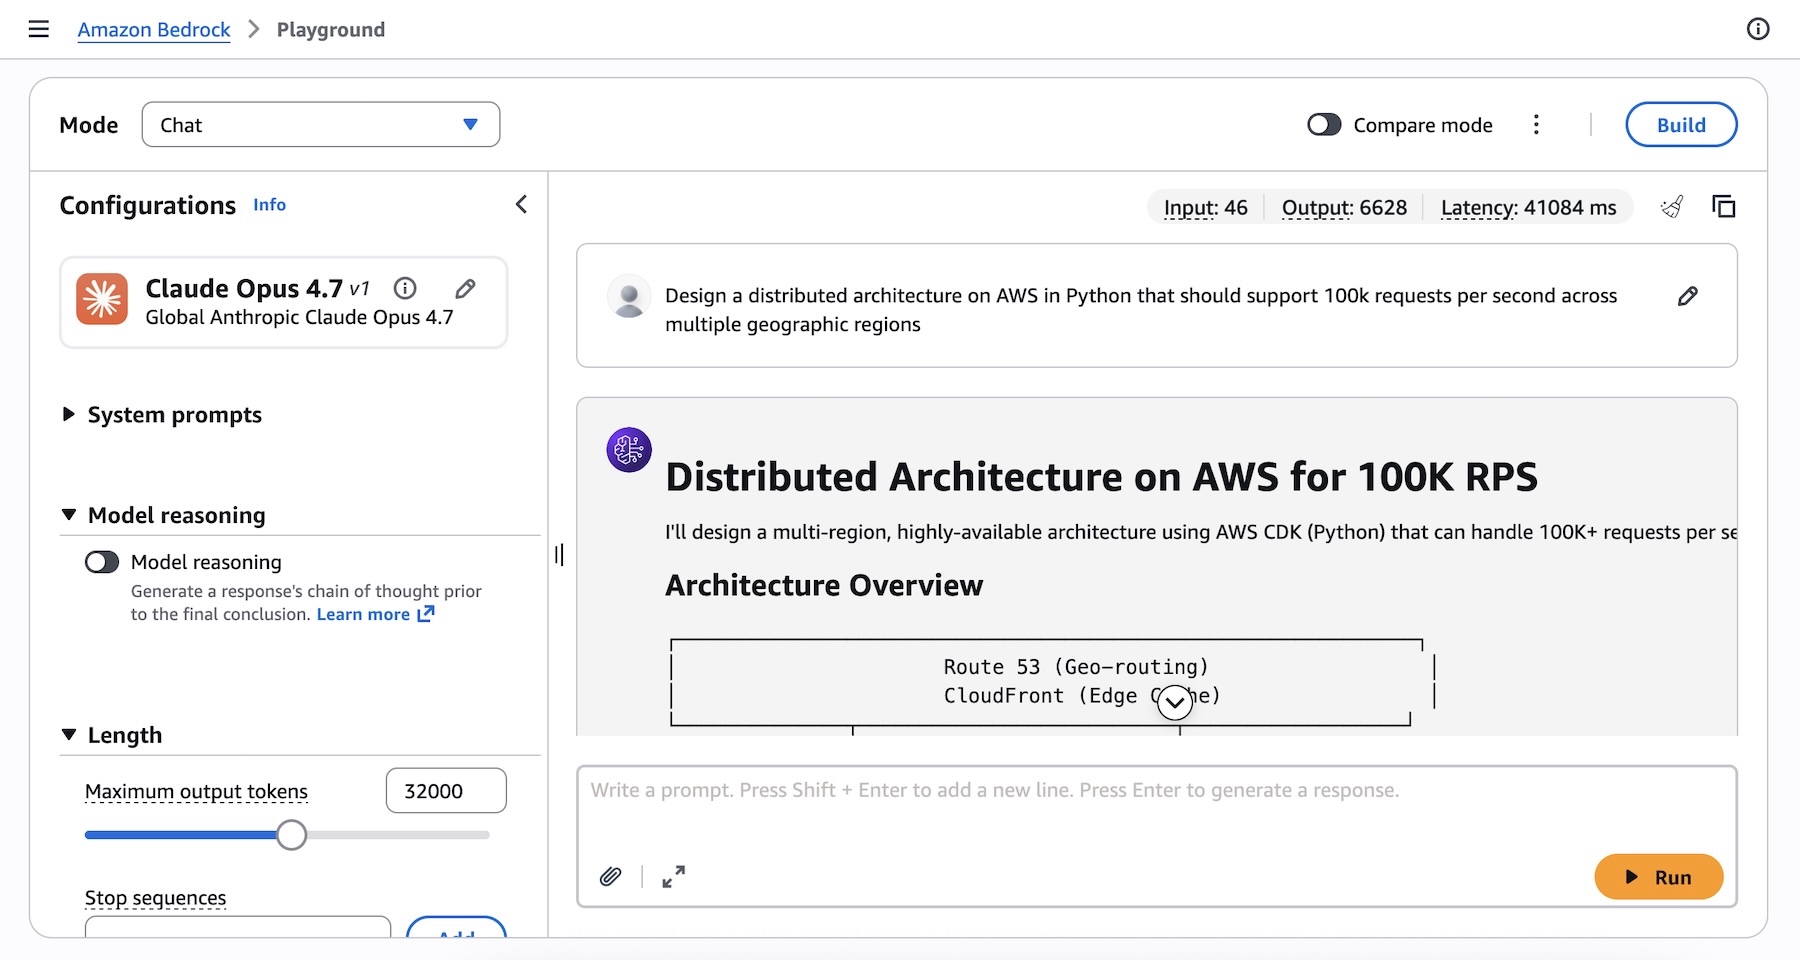
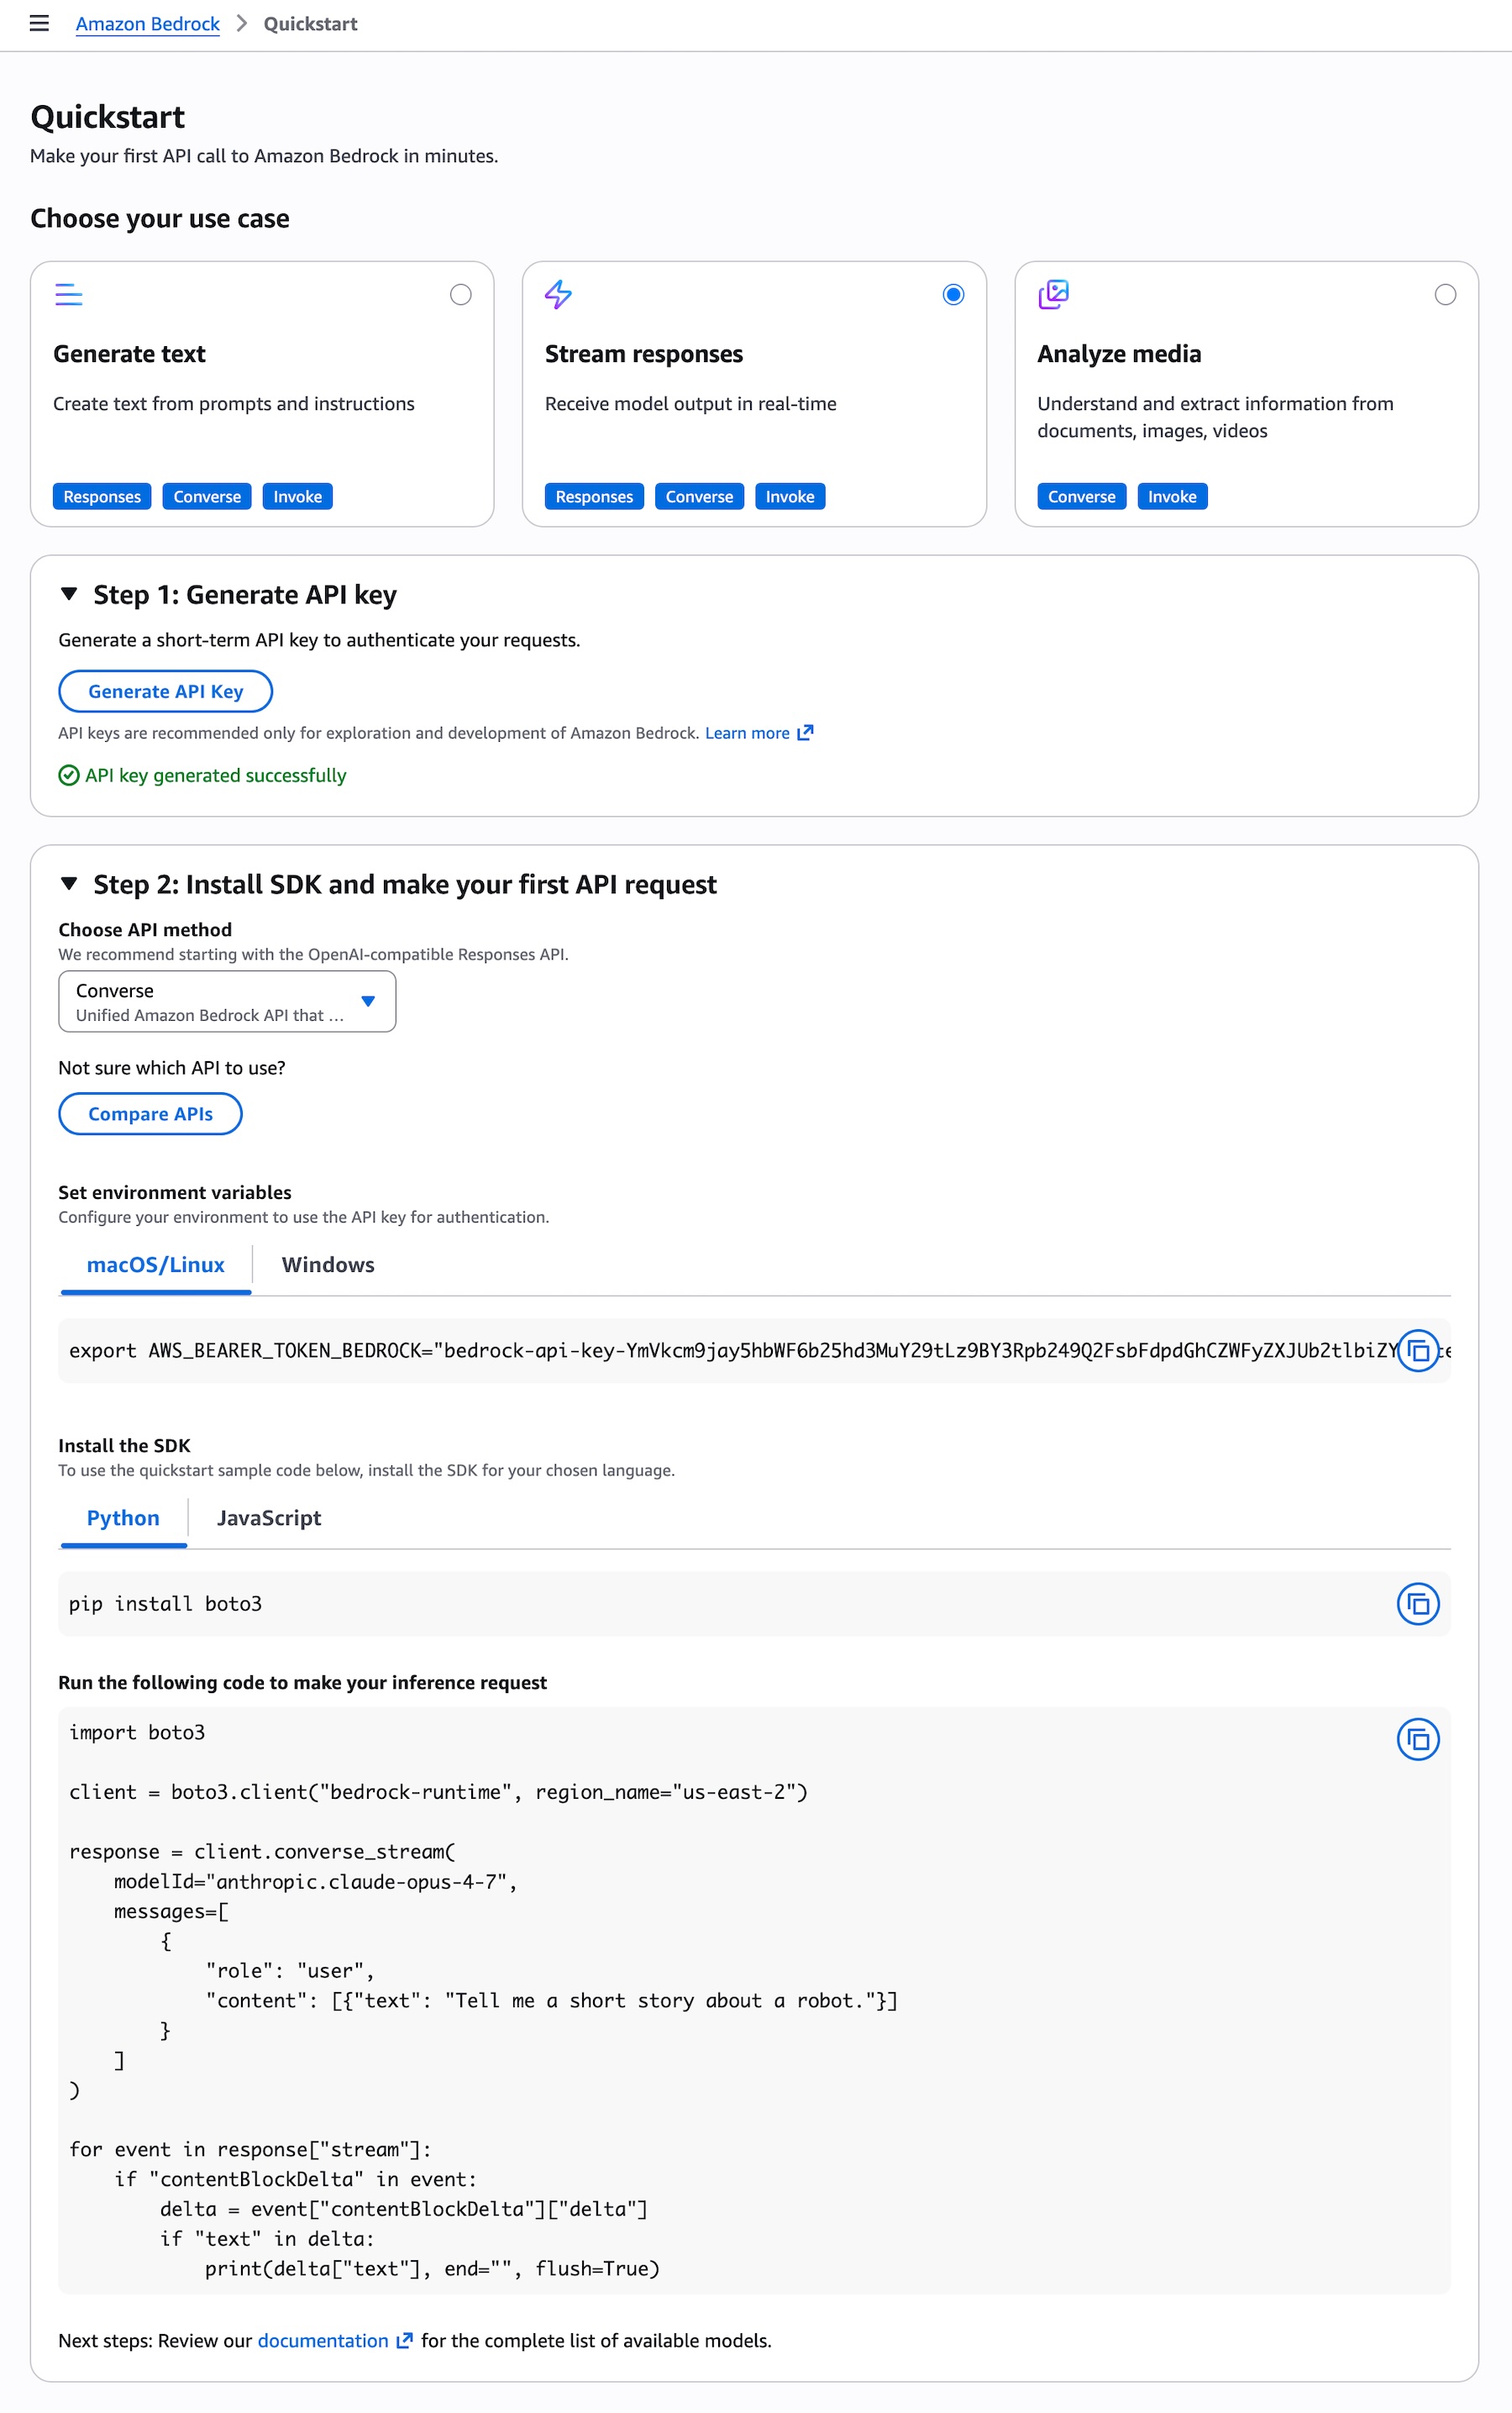
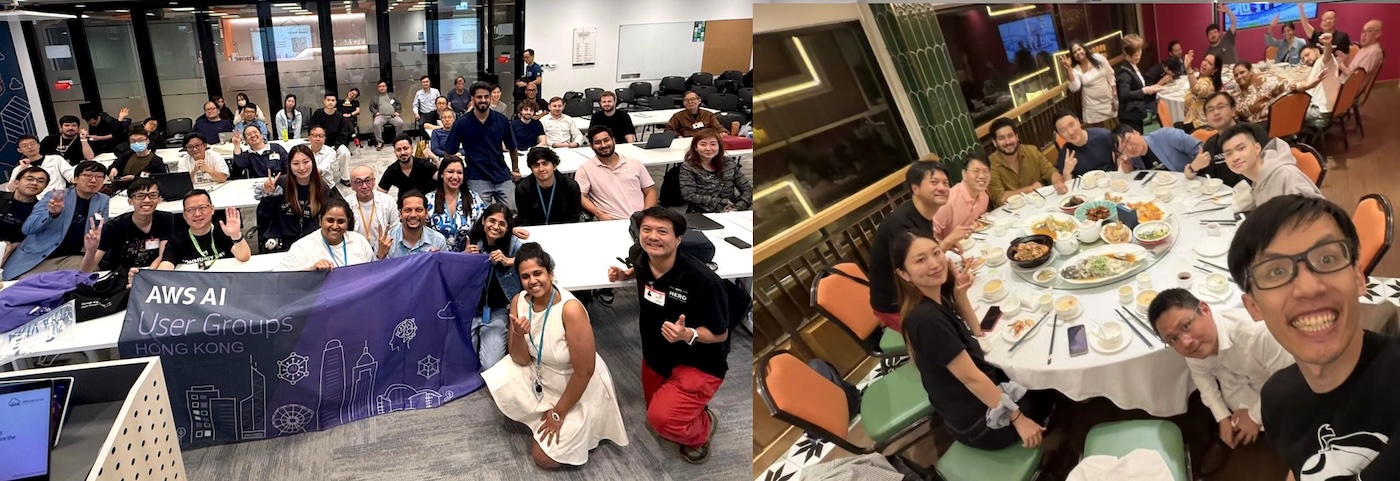
 At the last re:Invent, we introduced the