Tag Archives: Amazon Bedrock

Secure multi-tenant RAG with Amazon Bedrock and Verified Permissions

Post Syndicated from Rennay Dorasamy original https://aws.amazon.com/blogs/architecture/secure-multi-tenant-rag-with-amazon-bedrock-and-verified-permissions/

Large organizations building internal generative AI applications face a recurring challenge: controlling which teams or departments can access which documents, without duplicating infrastructure for each group. Within a single tenant, employees from a specific department should only access material assigned to that department. However, executives, with a wider span of control, will require access to material across multiple departments. Retrieval Augmented Generation (RAG) is one of several complementary techniques, including fine-tuning and continued pre-training, for customizing generative AI application responses with your data.

In an enterprise context, with fast-moving data and many users, RAG provides a middle ground between cost and performance. This post shows you how to use a single, shared Knowledge Base (KB) instance to reduce the cost and complexity of separate instances. You can update access rules in minutes without redeploying code and maintain a detailed audit trail of every authorization decision. You run a single RAG application that serves multiple departments, with document access evaluated at retrieval time.

Figure 1 illustrates the requirement.
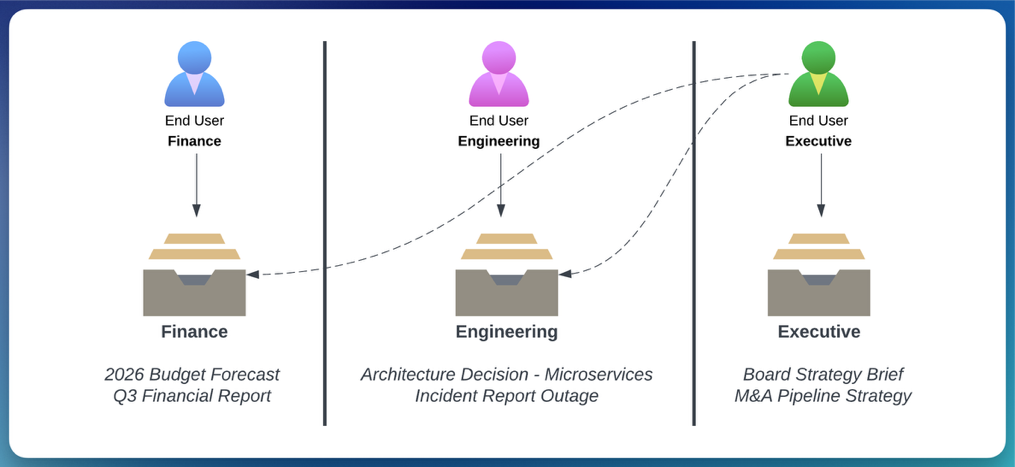
Role-level access to shared organizational data and resources

A previous post, Multi-tenancy in RAG applications in a single Amazon Bedrock knowledge base with metadata filtering, demonstrates how to use Amazon Simple Storage Service (Amazon S3) folder structures and metadata filtering to segregate data between tenants within a single knowledge base. That pattern works well for broad, tenant-level boundaries where the filter value is known at design time and embedded in application code. However, within a single tenant, different departments or roles often need different document visibility and executives may need cross-cutting access that spans multiple boundaries. This post extends that foundation by externalizing the filter selection logic into Cedar policies managed by Amazon Verified Permissions, allowing dynamic, runtime-evaluated authorization decisions.

This pattern lets a single RAG application serve many departments while keeping each department’s documents isolated, without standing up a knowledge base per team. It builds on metadata filtering in Amazon Bedrock Knowledge Bases, a fully managed RAG capability that handles ingestion, retrieval, and prompt augmentation through a single API. Metadata filtering is a strong foundation, but it creates a gap. Filter selection logic has no external governance, and changing the rules requires a code redeployment.

When authorization logic lives inside code, rules can become inconsistent over time and require a full deployment cycle to change. Amazon Verified Permissions addresses this by providing scalable, fine-grained authorization and permissions management for custom applications. Externalized Cedar policies in Verified Permissions are auditable, version-controlled, and updatable at runtime.

This post walks you through a two-layer, defense-in-depth authorization pattern for granular, intra-tenant access control in RAG applications. Defense in depth is a security strategy that uses multiple independent layers of protection. Each layer operates independently. If one layer is misconfigured, the other layer still enforces access control. The pattern runs on Amazon Bedrock, a fully managed service that offers a choice of high-performing foundation models (FMs) from Amazon and AI companies through a single API, along with a broad set of capabilities you need to build generative AI applications with security, privacy, and responsible AI.

In this post, you learn how to:

  1. Enforce fine-grained, document-level access control at retrieval time using a single Amazon Bedrock Knowledge Bases instance.
  2. Evaluate Cedar policies at runtime to dynamically construct the metadata filter passed to the RetrieveAndGenerate API.
  3. Update authorization rules without changing application code or triggering a deployment.
  4. Design a deny-by-default authorization system intended to deny access when the authorization service is unavailable.

Isolation model and scope

This pattern provides filter-level (logical) isolation, not IAM-enforced (infrastructure) isolation. Metadata filters control which documents are returned at retrieval time, but the underlying knowledge base remains a shared resource. If the middleware logic that constructs the filter were to fail open, documents from other groups would be exposed.

This pattern is designed for granular access control within a single tenant. For example, controlling which departments, teams, or roles within one organization can access which documents. It is not a substitute for hard tenant isolation in a multi-tenant SaaS product. For cross-tenant isolation where a compliance boundary is required between separate customers or organizations, provision a dedicated knowledge base per tenant with IAM-enforced resource boundaries. Within each tenant’s knowledge base, you can then layer this filter-based pattern for finer-grained access control.

Use this pattern when:

  • You need to control document access across departments, teams, or roles within a single organization.
  • Access rules change frequently and you want to update them without code redeployment.
  • You want a single knowledge base instance to reduce cost and operational overhead for intra-tenant document segregation.

Do not use this pattern when:

  • You require hard isolation between separate customers or organizations (use a knowledge base per tenant with IAM boundaries instead).
  • Your compliance or audit requirements mandate infrastructure-level separation between data sets.
  • A failure of the filter mechanism would constitute a regulatory breach (filter-level isolation is a logical boundary, not a physical one).

Residual risk, ingestion race condition: A brief window exists between document upload and sidecar creation. The ingestion safeguard (Step 1) reduces this by excluding documents without sidecars. However, if you modify the ingestion schedule to run continuously or with short intervals, verify that the batching window in Amazon Simple Queue Service (Amazon SQS) (default 30 seconds) provides sufficient time for the tagging Lambda to complete before the next ingestion cycle.

Prerequisites

Before implementing this pattern, you need:

  1. Familiarity with Python, AWS Lambda, and infrastructure as code concepts.
  2. An AWS account with AWS Identity and Access Management (AWS IAM) permissions to create AWS Lambda functions, an Amazon API Gateway REST API, Amazon Cognito user pools, Verified Permissions policy stores, and Amazon Bedrock Knowledge Bases.
  3. Amazon Cognito configured with department-based user groups (such as dept-a, dept-b, dept-c) and cognito:groups included in the JSON Web Token (JWT) issued to clients.
  4. Amazon Bedrock model access for the FMs you plan to use (such as Anthropic Claude 3 Haiku, and Amazon Nova Lite 2).
  5. A Verified Permissions policy store created and the Cedar schema defined (principals, resources, actions) before deployment.
  6. AWS Cloud Development Kit (AWS CDK) or AWS CloudFormation to deploy the infrastructure described in this walkthrough.
  7. Sample documents prepared with department prefixes (such as docs/dept-a/report.pdf) for upload to Amazon S3.

Important: Implementing this pattern creates billable AWS resources, including Amazon Bedrock Knowledge Bases, AWS Lambda functions, Amazon API Gateway, Amazon S3, Amazon Cognito, Amazon Verified Permissions, Amazon EventBridge, Amazon SQS, Amazon DynamoDB, AWS WAF, and Amazon CloudFront. Costs vary based on usage volume and AWS Region. Review AWS Pricing for each service before deploying and see the Cleaning up section at the end of this post to remove resources when testing is complete.

Solution overview

Serving many departments from one application shouldn’t mean giving every department access to every document. This solution keeps each department’s documents isolated inside a single Amazon Bedrock Knowledge Bases instance, so you avoid the cost and operational overhead of a knowledge base per team within that tenant. Metadata tags logically separate documents, and Verified Permissions acts as an externalized policy enforcement point, deciding which documents a user’s group or role is authorized to see on every request.

A key objective is to serve multiple departments within a single tenant from one Knowledge Base instance. If you had to provision a separate instance per department, it would multiply the infrastructure: separate data sources, ingestion pipelines and management overhead. A single knowledge base with metadata filtered access avoids this duplication while providing logical document isolation within the tenant boundary. Documents are logically separated by their metadata tags, and Verified Permissions provides a reliable, externalized policy enforcement point to determine which tags a user, in a specific group or role, is authorized to access.

The ingestion pipeline tags documents with department metadata. Verified Permissions evaluates Cedar policies at query time to determine which department tags you are permitted to see. A middleware service (implemented as an AWS Lambda function) converts that policy decision into a metadata filter and uses this in the Amazon Bedrock RetrieveAndGenerate API. This API combines the retrieval and generation steps, returning a grounded response based on the filtered document set. The FM only processes documents that passed the filter.

Two independent layers enforce authorization:

  • Layer 1 (API access): A Lambda Authorizer on Amazon API Gateway calls Verified Permissions to decide whether you can invoke the API at all.
  • Layer 2 (document access): A middleware Lambda, used to orchestrate the call to the Knowledge Base, also calls Verified Permissions to determine which Knowledge Base resources your department is permitted to query, then constructs a metadata filter accordingly.

Neither layer depends on the other for correctness. If Layer 1 were bypassed then Layer 2 is designed to enforce document-level isolation at the KB metadata filter.
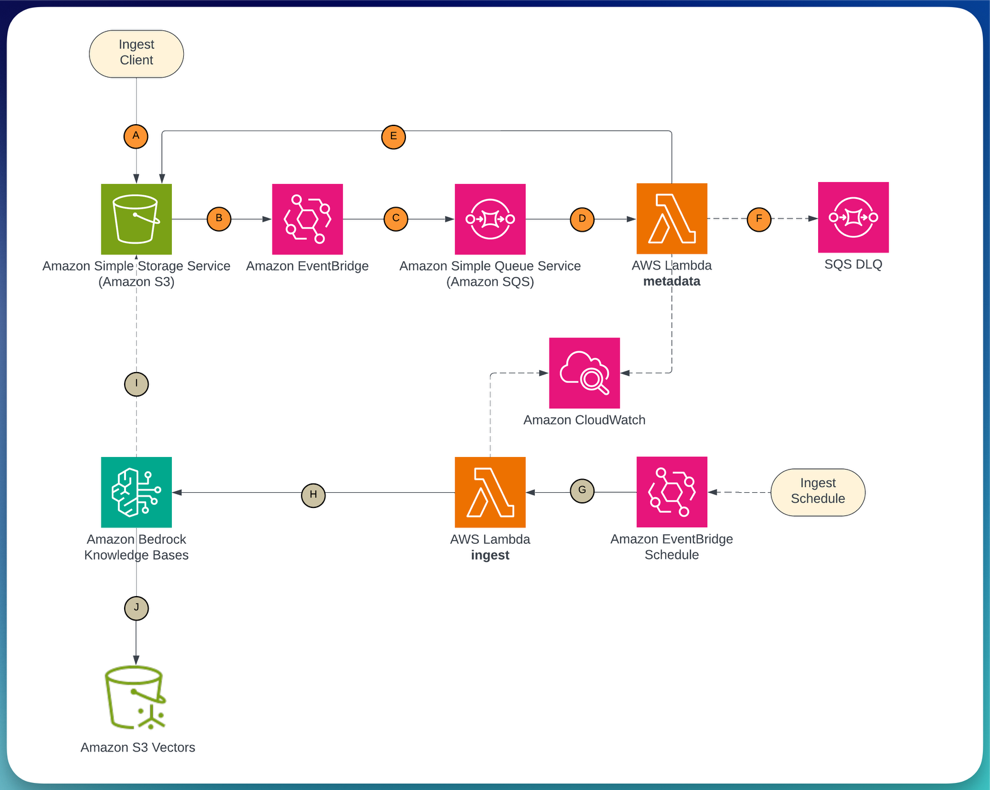
Ingestion pipeline showing documents uploaded to Amazon S3 triggering Amazon EventBridge, routing through Amazon SQS to an AWS Lambda function that writes metadata

Figure 2 shows the ingestion pipeline: documents uploaded to Amazon Simple Storage Service (Amazon S3) trigger Amazon EventBridge, which routes through Amazon Simple Queue Service (Amazon SQS) to an AWS Lambda function that writes metadata. A scheduled Lambda then triggers the Amazon Bedrock Knowledge Bases ingestion job.
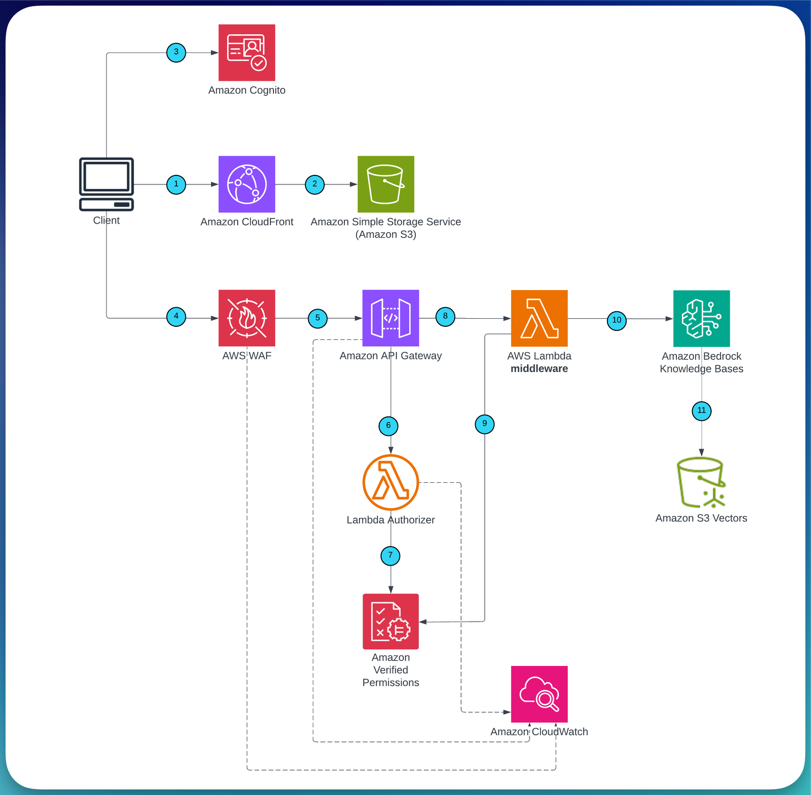
Query flow showing a user request passing through Amazon CloudFront, AWS WAF, Amazon API Gateway with Lambda Authorizer, and middleware Lambda to Amazon Bedrock Knowledge Bases

Figure 3 shows the query flow: a user request passes through Amazon CloudFront and AWS WAF to Amazon API Gateway, where the Lambda Authorizer evaluates Layer 1 (API-level) authorization against Verified Permissions. If permitted, the middleware Lambda evaluates Layer 2 (document-level) authorization, constructs the metadata filter, and calls RetrieveAndGenerate.

Authorization decision flow

Step Component Decision On deny
1 AWS WAF Rate limit and rule check Request blocked
2 Lambda Authorizer (Layer 1) Can you invoke the API? 403 returned
3 Middleware Lambda (Layer 2) Which departments can you access? Empty result set
4 Amazon Bedrock Knowledge Bases Metadata filter applied to retrieval Unauthorized docs excluded
5 Guardrails for Amazon Bedrock Response grounded in retrieved context? Response blocked or modified

Key AWS services

Layer Service Role
Identity layer Amazon Cognito Issues JWTs with department group claims (cognito:groups) from the user pool
API security layer AWS WAF Applies rate limiting, IP filtering, and managed rule evaluation at the edge
Layer 1 authorization Amazon Verified Permissions Evaluates Cedar policies for API-level access decisions in the Lambda Authorizer
Layer 2 authorization Amazon Verified Permissions Evaluates Cedar policies for document-level access and drives metadata filter construction
RAG retrieval and FM invocation layer Amazon Bedrock Knowledge Bases Fully managed RAG capability that handles retrieval with metadata filtering and FM generation in a single API call
Ingestion layer Amazon EventBridge, Amazon SQS Event-driven pipeline for metadata sidecar tagging; Amazon SQS buffers upload spikes and routes failures to a dead-letter queue

Technical implementation

The walkthrough presents ingestion pipeline first to tag and index your documents. You then move on to the Query Flow which contains the core authorization pattern. Each section following maps to a distinct component in the architecture.

Step 1: Set up the event-driven ingestion pipeline with metadata tagging

For the metadata filter to work at query time, documents need to be tagged with their department before they are indexed. The ingestion pipeline handles this in two phases.

Phase 1 (event-driven): When a document is uploaded to Amazon S3 under a department prefix (such as docs/dept-a/report.pdf), Amazon EventBridge fires an ObjectCreated event. The event routes through Amazon SQS to an AWS Lambda function that writes a .metadata.json sidecar file alongside the document.

The Amazon SQS queue buffers bulk uploads and routes failed tagging attempts to a dead-letter queue for retry.

Phase 2 (scheduled): An Amazon EventBridge schedule triggers an ingestion Lambda every five minutes, which calls the StartIngestionJob API on the Amazon Bedrock Knowledge Bases data source. Amazon Bedrock reads the documents and their sidecars from Amazon S3, chunks them, generates embeddings, and indexes the vectors with the department attribute.

# Validate sidecar presence before ingestion
objects = s3.list_objects_v2(Bucket=BUCKET, Prefix=f"docs/{dept}/")
docs = [o["Key"] for o in objects.get("Contents", []) if not o["Key"].endswith(".metadata.json")]
for doc_key in docs:
    sidecar_key = f"{doc_key}.metadata.json"
    try:
        s3.head_object(Bucket=BUCKET, Key=sidecar_key)
    except s3.exceptions.ClientError:
        logger.warning(f"Skipping {doc_key}: no metadata sidecar found")
        docs.remove(doc_key)

Tamper detection for metadata sidecars: Enable S3 Versioning on the document bucket and configure AWS CloudTrail S3 data events to log PutObject and DeleteObject calls. Create an Amazon CloudWatch Alarms metric filter that alerts when a PutObject to a .metadata.json key originates from principals other than the tagging Lambda role. For workloads with strict compliance requirements, consider S3 Object Lock in compliance mode to make sidecars immutable after creation – noting that document re-classification would then require a deliberate workflow to create a new version.

Upload prefix enforcement: The metadata tagging Lambda derives the department label from the S3 key prefix (for example, docs/dept-a/ → department: dept-a). To help prevent a user or process from uploading documents under another department’s prefix, scope upload permissions using an IAM policy condition:

{
    "Effect": "Allow",
    "Action": "s3:PutObject",
    "Resource": "arn:aws:s3:::your-doc-bucket/docs/dept-a/*",
    "Condition": {
        "StringEquals": {
            "aws:PrincipalTag/department": "dept-a"
        }
    }
}

Each upload principal (whether a user role, CI/CD pipeline, or application) should carry a department tag that matches its permitted prefix. This helps prevent the tagging Lambda from being tricked into mislabeling a document by an upload to the wrong path.

Ingestion safeguard: Before triggering the ingestion job, the scheduling Lambda lists objects under each department prefix and verifies that every document has a corresponding .metadata.json sidecar. Documents without a sidecar are excluded from the ingestion scope and logged to CloudWatch as untagged. This helps prevent an untagged document from being indexed without a department attribute, which could cause it to bypass metadata filters at query time. If your workload requires stricter guarantees, move untagged documents to a quarantine prefix and alert via Amazon Simple Notification Service (Amazon SNS).

S3 write restriction: Restrict s3:PutObject permission on the document bucket to the metadata tagging Lambda’s IAM execution role. All other principals – including application roles, CI/CD pipelines, and human operators should have at most s3:GetObject and s3:ListBucket. This helps prevent accidental or malicious modification of .metadata.json sidecar files, which could re-tag a document under a different department and expose it to unauthorized users on the next ingestion cycle. Use a bucket policy with an explicit deny for s3:PutObject that exempts only the tagging Lambda’s role ARN:

{
    "Effect": "Deny",
    "Principal": "*",
    "Action": ["s3:PutObject", "s3:DeleteObject"],
    "Resource": "arn:aws:s3:::your-doc-bucket/*",
    "Condition": {
        "StringNotEquals": {
            "aws:PrincipalArn": "arn:aws:iam::123456789012:role/MetadataTaggingLambdaRole"
        }
    }
}

A 30-second batching window on the Amazon SQS event source means bulk uploads are processed together rather than one document per Lambda invocation. The two-phase separation helps confirm that department metadata sidecars are written before the ingestion job runs, reducing the risk of a race condition where a document might be indexed without a department tag.

# metadata_lambda/handler.py
import boto3, json

def handler(event, context):
    for record in event["Records"]:
        body = json.loads(record["body"])
        s3_key = body["detail"]["object"]["key"]
        # Extract department from prefix: docs/dept-a/report.pdf -> dept-a
        dept = s3_key.split("/")[1]
        meta_key = s3_key + ".metadata.json"
        s3 = boto3.client("s3")
        s3.put_object(
            Bucket=BUCKET,
            Key=meta_key,
            Body=json.dumps({"metadataAttributes": {"department": dept}})
        )

Implementation note: Deploy this as the handler for your metadata tagging AWS Lambda function (Python 3.12 runtime). Set the BUCKET environment variable. The function’s IAM execution role requires s3:PutObject permission on the document bucket.

Step 2: Configure Amazon Bedrock Knowledge Bases

With Amazon Bedrock Knowledge Bases, you configure document chunking, embedding model selection, vector indexing, and metadata filtering without managing the underlying infrastructure. You configure a data source backed by the same Amazon S3 bucket as the ingestion pipeline.

Amazon Bedrock Knowledge Bases chunks documents at 300 tokens with 20% overlap (the default, which works well for structured enterprise documents). An embedding model, such as Amazon Titan Text Embeddings V2, generates the embeddings. The metadata attributes defined in the .metadata.json sidecar files are indexed alongside the vectors, making them available as pre-filters on the RetrieveAndGenerate call.

Step 3: Define the Cedar schema and policies in Amazon Verified Permissions

Verified Permissions provides fine-grained authorization through Cedar, a purpose-built policy language. The Cedar schema defines three entity types for this solution:

  1. Principal: GenAIApp::UserGroup (the department group extracted from the JWT)
  2. Action: query (retrieves documents from a knowledge base) and invokeModel (calls an FM)
  3. Resource: GenAIApp::KnowledgeBase and GenAIApp::Model

The namespace GenAIApp is a custom prefix you define when creating the Cedar schema. You can replace it with your own application namespace (such as MyCompany or RAGApp).

The following six policies cover the three departments used in this walkthrough. Department C has a cross-department access grant that covers each Knowledge Base resource, which suits a leadership or executive group:

// dept-a: query own knowledge base + use Claude 3 Haiku
permit(
    principal in GenAIApp::UserGroup::"dept-a",
    action == GenAIApp::Action::"query",
    resource == GenAIApp::KnowledgeBase::"dept-a"
);

permit(
    principal in GenAIApp::UserGroup::"dept-a",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"anthropic.claude-3-haiku-20240307-v1:0"
);

// dept-b: query own knowledge base + use Claude 3 Haiku
permit(
    principal in GenAIApp::UserGroup::"dept-b",
    action == GenAIApp::Action::"query",
    resource == GenAIApp::KnowledgeBase::"dept-b"
);

permit(
    principal in GenAIApp::UserGroup::"dept-b",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"anthropic.claude-3-haiku-20240307-v1:0"
);

// dept-c: cross-department access + use Amazon Nova Lite 2
permit(
    principal in GenAIApp::UserGroup::"dept-c",
    action == GenAIApp::Action::"query",
    resource
);

permit(
    principal in GenAIApp::UserGroup::"dept-c",
    action == GenAIApp::Action::"invokeModel",
    resource == GenAIApp::Model::"amazon.nova-2-lite-v1:0"
);

To adapt these policies for your organization, replace the department identifiers (dept-a, dept-b, dept-c) with your own group names. The pattern supports multiple access models: per-team, per-project, or hierarchical. For temporary access grants, add a Cedar policy with a when condition that evaluates a time-based attribute, and remove the policy when access should expire.

Policy changes take effect on the next API call. You do not need a Lambda redeployment or AWS CDK update.

Policy governance: Because Cedar policy changes take effect immediately, restrict who can modify policies in production. Apply IAM conditions on verifiedpermissions:CreatePolicy, UpdatePolicy, and DeletePolicy so that only a dedicated CI/CD pipeline role or a small set of authorized administrators can mutate the policy store. Enable AWS CloudTrail logging for Verified Permissions API calls and create a CloudWatch Alarm that triggers when policy mutation events occur outside your change management workflow. For production deployments, validate Cedar policies against test scenarios in a non-production policy store before promoting them. Treat policy changes with the same rigor as application code deployments.

Step 4: Configure Layer 1: API-level authorization (Lambda Authorizer)

When a request arrives at Amazon API Gateway, the Lambda Authorizer runs before your application logic. It validates the JWT signature against the Amazon Cognito JSON Web Key Set (JWKS) endpoint, then calls Verified Permissions IsAuthorized with your group membership. This is the traditional “authorization/access level” check: it verifies that you are allowed to invoke the API, not which documents you can access.

The authorizer denies access by default. If Verified Permissions is unavailable, the function raises an exception and Amazon API Gateway returns a 403.

import boto3, json

avp = boto3.client("verifiedpermissions")

def handler(event, context):
    token = event["authorizationToken"]
    claims = decode_and_verify_jwt(token)  # validates against Amazon Cognito JWKS
    groups = claims.get("cognito:groups", [])

    if not groups:
        raise Exception("Unauthorized")

    # Evaluate each group; allow if any group has a permit policy
    allowed = False
    for group in groups:
        response = avp.is_authorized(
            policyStoreId=POLICY_STORE_ID,
            principal={"entityType": "GenAIApp::UserGroup", "entityId": group},
            action={"actionType": "GenAIApp::Action", "actionId": "query"},
            resource={"entityType": "GenAIApp::Application", "entityId": "api"}
        )
        if response["decision"] == "ALLOW":
            allowed = True
            break

    if not allowed:
        raise Exception("Unauthorized")

    return generate_policy("Allow", event["methodArn"], claims)

Implementation note: Deploy this as a Lambda Authorizer (TOKEN type) on your Amazon API Gateway REST API. Set the TTL on the authorizer cache to 0 during testing so that policy changes take effect immediately.

Production cache TTL: In production, the API Gateway authorizer cache TTL controls how quickly policy revocations take effect. A TTL of 0 means every request triggers a fresh Verified Permissions evaluation. Revocations are immediate but latency increases. A TTL of 300 seconds (the API Gateway default) improves latency but means a revoked policy could continue to permit access for up to 5 minutes. For workloads where timely revocation matters (for example an employee offboarding or incident response), set the TTL to 0 or a deliberately short value (for example, 30–60 seconds) and accept the additional Verified Permissions API calls. The claim that “policy changes take effect on the next API call” holds true only when the authorizer cache TTL is zero or the cached entry has expired.

Multi-group membership: A user may belong to more than one Cognito group. For example, an employee who is a member of both dept-a and a cross-functional leadership group. The authorizer evaluates the group memberships present in the JWT and permits the API call if a group has a matching Cedar permit policy. This helps prevent arbitrary access restrictions based on the order in which groups appear in the token. Document-level access is then determined independently at Layer 2, where the middleware evaluates each department resource against the user’s groups to construct the appropriate metadata filter.

For error handling patterns, implement exponential backoff with jitter on the Verified Permissions API call. Log authorization decisions to Amazon CloudWatch for monitoring and auditing.

Step 5: Configure Layer 2: Document-level authorization (middleware Lambda)

Once a request passes Layer 1, the middleware Lambda runs a second, independent Verified Permissions evaluation. This time, it checks which KB resources you are permitted to query based on your group membership, then translates the decision directly into a metadata filter on the RetrieveAndGenerate call.

Amazon Bedrock Knowledge Bases applies the metadata filter before the vector similarity search runs. This means the FM processes only documents you are authorized to access. The filter helps prevent unauthorized documents from appearing in the retrieval set.

Department access model

Group Foundation model Knowledge base access
dept-a Claude 3 Haiku Department A documents only
dept-b Claude 3 Haiku Department B documents only
dept-c Amazon Nova Lite 2 Multiple departments (A, B, and C)
def build_filter_and_invoke(user_group, query, session_id):
    permitted_depts = []
    for dept in ["dept-a", "dept-b", "dept-c"]:
        resp = avp.is_authorized(
            policyStoreId=POLICY_STORE_ID,
            principal={"entityType": "GenAIApp::UserGroup",
                       "entityId": user_group},
            action={"actionType": "GenAIApp::Action",
                    "actionId": "query"},
            resource={"entityType": "GenAIApp::KnowledgeBase",
                      "entityId": dept}
        )
        if resp["decision"] == "ALLOW":
            permitted_depts.append(dept)

    if not permitted_depts:
        raise PermissionError("No permitted Knowledge Base resources")

    # Implement retry with exponential backoff on avp.is_authorized calls

    # Build metadata filter based on permitted departments
    if len(permitted_depts) == 1:
        kb_filter = {"equals": {"key": "department",
                                "value": permitted_depts[0]}}
    else:
        kb_filter = {"orAll": [{"equals": {"key": "department",
                                           "value": d}}
                               for d in permitted_depts]}

    return bedrock_agent.retrieve_and_generate(
        input={"text": query},
        retrieveAndGenerateConfiguration={
            "type": "KNOWLEDGE_BASE",
            "knowledgeBaseConfiguration": {
                "knowledgeBaseId": KB_ID,
                "modelArn": get_permitted_model(user_group),
                "retrievalConfiguration": {
                    "vectorSearchConfiguration": {
                        "filter": kb_filter
                    }
                }
            }
        }
    )

Implementation note: Deploy this as the handler for your middleware AWS Lambda function (Python 3.12 runtime). Set environment variables POLICY_STORE_ID and KB_ID. The function’s IAM execution role requires verifiedpermissions:IsAuthorized and bedrock:RetrieveAndGenerate permissions.

The FM selection uses the same Verified Permissions policy store. Cedar policies that grant invokeModel access determine which model ID the middleware passes to Amazon Bedrock, so model access control is driven by the same externalized policies as document access.

Security note: The metadata filter excludes unauthorized documents from the retrieval set before the FM processes them. If a user queries for another department’s data, the request returns no relevant results. To monitor for unexpected retrieval behavior, use Amazon CloudWatch logging on the middleware AWS Lambda function.

Benefits of two independent authorization layers

Layer 1 (API Gateway) Layer 2 (Middleware Lambda)
Question answered Can you invoke the API? Which documents can your department access?
Enforcement point Before application logic runs At Amazon Bedrock Knowledge Bases metadata filter
Failure mode 403 returned to you Empty or filtered result set

Availability trade-off: Both layers depend on Amazon Verified Permissions. If the service is throttled or unavailable, the deny-by-default design means users are denied access. This is the correct and intended secure behavior. For most workloads, a brief period of denial is preferable to failing open. If your application has strict availability requirements, consider implementing exponential backoff with jitter on all IsAuthorized calls (in both the Lambda Authorizer and the middleware Lambda) to handle transient throttling gracefully. A circuit-breaker that falls back to cached last-known-good authorization decisions can improve availability, but introduces a window where revoked access may still be honored. Document this trade-off explicitly if you adopt it, and make sure cached decisions expire on a short TTL.

Step 6: Add Guardrails for Amazon Bedrock as an output safety layer

Guardrails for Amazon Bedrock applies contextual source fidelity checks and content filtering as a complementary safety layer. Where Verified Permissions controls which documents the FM accesses, Guardrails evaluates the FM’s response before it’s returned to you.

Contextual source fidelity checks help confirm that the response stays faithful to the retrieved documents rather than drawing from the FM’s pre-training data. Combine this with the metadata filter from Layer 2 for a complete defense in depth approach: authorization restricts the retrieval set, and Guardrails validates the generated output.

The Guardrail configuration in the RetrieveAndGenerate call applies two checks:

  1. Contextual grounding: Helps limit responses that extrapolate beyond the retrieved context. This supports factual accuracy tied to your documents.
  2. Content filtering: Blocks responses containing harmful or inappropriate content based on your configured thresholds.

You apply the Guardrail in the RetrieveAndGenerate call by passing the guardrailConfiguration parameter with your Guardrail ID and version. Contextual grounding helps mitigate prompt injection by limiting responses to the retrieved context but does not eliminate all injection vectors. For additional defense, validate input length and sanitize queries before passing them to RetrieveAndGenerate. For more information, see the Guardrails for Amazon Bedrock documentation.

Step 7: Test the end-to-end authorization flow

With the solution deployed, here is what happens when a dept-a user submits a query:

  1. A user submits a query using a web application with Authorization: Bearer through Amazon CloudFront to AWS WAF.
  2. AWS WAF applies rate limiting and managed rules, then forwards clean traffic to Amazon API Gateway.
  3. The Lambda Authorizer validates the JWT and calls Verified Permissions. The dept-a group has a query permit policy, so the call is allowed.
  4. The middleware Lambda calls Verified Permissions for each Knowledge Base resource. Only dept-a is permitted, so the filter {“equals”: {“key”: “department”, “value”: “dept-a”}} is constructed.
  5. The middleware calls RetrieveAndGenerate with the metadata filter applied. Amazon Bedrock Knowledge Bases filters the document set before running the vector similarity search.
  6. Department B and C documents are excluded from the search space. The FM generates a response that stays grounded only in Department A documents.
  7. The response is checked by Guardrails for Amazon Bedrock before it is returned.

To test, use the following curl command with a valid JWT from Amazon Cognito:

curl -X POST https://<api-id>.execute-api.<region>.amazonaws.com/prod/query \
  -H "Authorization: Bearer <id_token>" \
  -d '{"query": "Summarize the latest department report"}'

A successful dept-a request returns a response grounded in Department A documents only. If authorization fails at Layer 1, you receive a 403 response. If Layer 2 finds no permitted resources, the function returns a PermissionError.

Monitor authorization decisions in Amazon CloudWatch Logs for both the Lambda Authorizer and middleware functions. Set up CloudWatch metric filters and alarms for the following:

  • Authorization deny rate (Layer 1 and Layer 2) – a spike may indicate credential probing, misconfigured clients, or a policy error.
  • Verified Permissions latency – sustained increases may signal throttling.
  • SQS dead-letter queue message count – messages in the DLQ indicate failed metadata tagging events that need attention.
  • Ingestion job failure rate – alerts you to documents that were not indexed.

AWS CloudTrail automatically logs Verified Permissions IsAuthorized calls, providing an audit trail of every authorization decision without additional configuration.

To observe the live policy update behavior, grant a dept-a Cedar policy that allows access to dept-b resources, then immediately resubmit the query. The next API call reflects the change. Revoke the policy and the restriction is restored on the following call.

Single knowledge base with metadata isolation

Adding a department requires adding a Cedar policy and tagging new documents. You do not need to provision additional infrastructure, deploy new stacks, or manage separate ingestion pipelines. The FM is presented with only the authorized document subset based on the applied metadata pre-filter.

For session management, use an Amazon DynamoDB table with a session TTL to maintain conversation context across requests. The RetrieveAndGenerate API accepts a sessionId parameter that manages multi-turn context automatically. Generate session IDs using a cryptographically random value (for example, uuid4) and bind each session to the authenticated user’s identity and group at creation time.

On every subsequent request, validate that the bearer token’s subject and group claims match the session owner before continuing the conversation. Invalidate sessions when a user’s group membership changes or their token is revoked and set a TTL appropriate to your use case (for example, 30 minutes of inactivity).

Cleaning up

If you deployed resources individually, delete them in the following order to avoid dependency errors:

  1. Amazon CloudFront distribution and AWS WAF web ACL.
  2. Amazon API Gateway REST API (this also removes the Lambda Authorizer association).
  3. AWS Lambda functions (metadata tagging, authorizer, middleware).
  4. Amazon Bedrock Knowledge Base and its associated data source.
  5. Amazon S3 bucket — empty the bucket first. If versioning is enabled, delete all object versions and delete markers before removing the bucket.
  6. Amazon EventBridge rule and Amazon SQS queue.
  7. Amazon DynamoDB table.
  8. Amazon Verified Permissions policy store.
  9. Amazon Cognito user pool (if created specifically for this pattern).
  10. IAM roles and policies created for the Lambda functions and API Gateway.
  11. Amazon CloudWatch log groups for each Lambda function.

Warning: Deleting these resources is irreversible. Back up any documents in S3, DynamoDB data, or Verified Permissions policies you may need before proceeding.

Conclusion

You now have a working defense-in-depth authorization pattern for granular, intra-tenant document access control in RAG applications that you built on Amazon Bedrock. With this approach, you can: change access policies at runtime without redeploying code, maintain logical document-level isolation that remains effective even if the API layer is misconfigured, and audit every authorization decision from a single Verified Permissions policy store.

Key takeaways

  • Updates without redeployment. Cedar policies in Verified Permissions are human-readable, version-controlled outside your Lambda code, and take effect on the next API call. You can revoke a department’s access or grant cross-department access to an executive group by updating a policy in the Verified Permissions console.
  • Cost-effective document isolation without infrastructure duplication. A single Amazon Bedrock Knowledge Bases instance with metadata pre-filtering delivers logical isolation between departments within a tenant, at a fraction of the cost and operational overhead of separate instances. Note that this is filter-level isolation, not infrastructure-level isolation – for hard tenant boundaries, use a dedicated knowledge base per tenant.
  • Independent enforcement layers help reduce the risk of a single point of failure. Layer 1 (Lambda Authorizer) and Layer 2 (middleware Lambda) enforce independent policy checks. Both call Verified Permissions separately, and both fail closed (deny by default).

Next steps

To extend this pattern further:

  1. Recommended first step: Test with your own documents. Replace the sample department documents with your own content, upload them under the appropriate prefix, and verify that the metadata filter isolates them correctly.
  2. Add a fourth department. Create a new Cedar policy, add a user group in Amazon Cognito, and upload tagged documents to validate that the pattern scales without code changes.
  3. Extend to agent tool authorization with Amazon Bedrock AgentCore. The Policy feature uses the same Cedar language to enforce fine-grained authorization on agent tool calls and gateways.
  4. Add attribute-based access control (ABAC). Extend Cedar policies to evaluate user attributes beyond group membership, such as project assignment, clearance level, or geographic location.
  5. Integrate with your identity provider. Replace Amazon Cognito with your enterprise identity provider (such as Okta or Microsoft Entra ID) by configuring a Verified Permissions identity source.
  6. Automate policy testing. Build a Continuous Integration/Continuous Deployment (CI/CD) pipeline that validates Cedar policies against test scenarios before deploying them to the policy store.
  1. Multi-tenancy in RAG applications in a single Amazon Bedrock knowledge base with metadata filtering (AWS Machine Learning Blog, April 2025)
  2. Amazon Verified Permissions documentation
  3. Amazon Bedrock Knowledge Bases documentation
  4. Amazon Bedrock Knowledge Bases with metadata filtering (AWS Machine Learning Blog, July 2024)
  5. Design secure generative AI application workflows with Amazon Verified Permissions and Amazon Bedrock Agents (AWS Machine Learning Blog, October 2024)
  6. Authorizing access to data with RAG implementations (AWS Security Blog, September 2025)
  7. Cedar policy language documentation
About the authors

Modernizing financial analytics with Amazon SageMaker Unified Studio

Post Syndicated from Umang Aggarwal original https://aws.amazon.com/blogs/architecture/modernizing-financial-analytics-with-amazon-sagemaker-unified-studio/

Avanse Financial Services is one of India’s leading education loan providers. Their Data Engineering Team had built a data lake on AWS using Amazon Simple Storage Service (Amazon S3), Amazon Athena, and AWS Glue for data ingestion and processing. However, their analytics and reporting layer ran on an external analytics application that wasn’t integrated with AWS. Data had to be copied from Amazon S3 into this external application before analysts could run any report, its license consumed a significant portion of their budget despite low utilization, and every integration with AWS services required custom-built pipelines.

After evaluating their options, Avanse migrated to a cloud-native lakehouse architecture using Amazon SageMaker Unified Studio, which unified their data engineering, analytics, and artificial intelligence (AI) workflows in a single governed environment on AWS. In this post, we walk through their migration journey so you can adapt their approach to your own environment.

Why Avanse chose to modernize

The separation between their AWS data lake and their external analytics application created five problems:

  1. Daily data synchronization bottleneck. Every report required a 4-hour batch copy from Amazon S3 into the external analytics application before analysts could query it. Business decisions were based on data that was at least a day old.
  2. Fixed licensing costs disconnected from usage. The external analytics application charged an annual fee regardless of how many queries analysts ran. Avanse needed usage-based pricing that matched what they actually consumed, not a fixed fee for capacity they weren’t using.
  3. Limited auditability. The external analytics application ran on a shared server where different business units (risk, collections, portfolio management) shared the same resources. It lacked granular audit trails, making it difficult to trace who accessed what data and when, or to allocate costs per team.
  4. No centralized data discovery. Although AWS Glue Data Catalog managed schema metadata for the data lake, the external analytics application couldn’t access it. Analysts working in that application relied on folder structures and manual documentation to find the right datasets, slowing onboarding and increasing the risk of using outdated data.
  5. Disconnected from AWS services. The external analytics application couldn’t query data in Amazon S3 or use AWS Glue catalogs natively. Every data flow required connectors and custom-built pipelines, adding maintenance overhead.

Additionally, some datasets were stored on Network File System (NFS) storage outside of Amazon S3, creating another data silo that needed to be consolidated.

Avanse chose Amazon SageMaker Unified Studio because it addressed all five challenges: direct querying of data in Amazon S3 avoiding synchronization, usage-based compute through Amazon Athena and Amazon EMR Serverless, project-based isolation with per-project billing, lineage tracking with AWS IAM Identity Center, and native integration with their existing AWS services.

Solution overview

The core architectural change was moving from a two-application model to a single integrated stack:

Previous architecture
Avanse’s data ingestion and processing ran on AWS (Amazon S3, AWS Glue, Athena), but analytics and reporting ran on an external analytics application. Data had to be batch-copied from Amazon S3 into this external application daily before analysts could query it. Each system had its own access controls, and there was no shared catalog or lineage tracking between them.
New architecture
Analytics now run directly against data in Amazon S3 through Amazon SageMaker Unified Studio. There’s no data copy step. Analysts query the same data that the ingestion pipelines produce, using Athena for SQL and EMR Serverless for large-scale processing. Governance, access control, and lineage are centralized through IAM Identity Center and SageMaker Catalog.

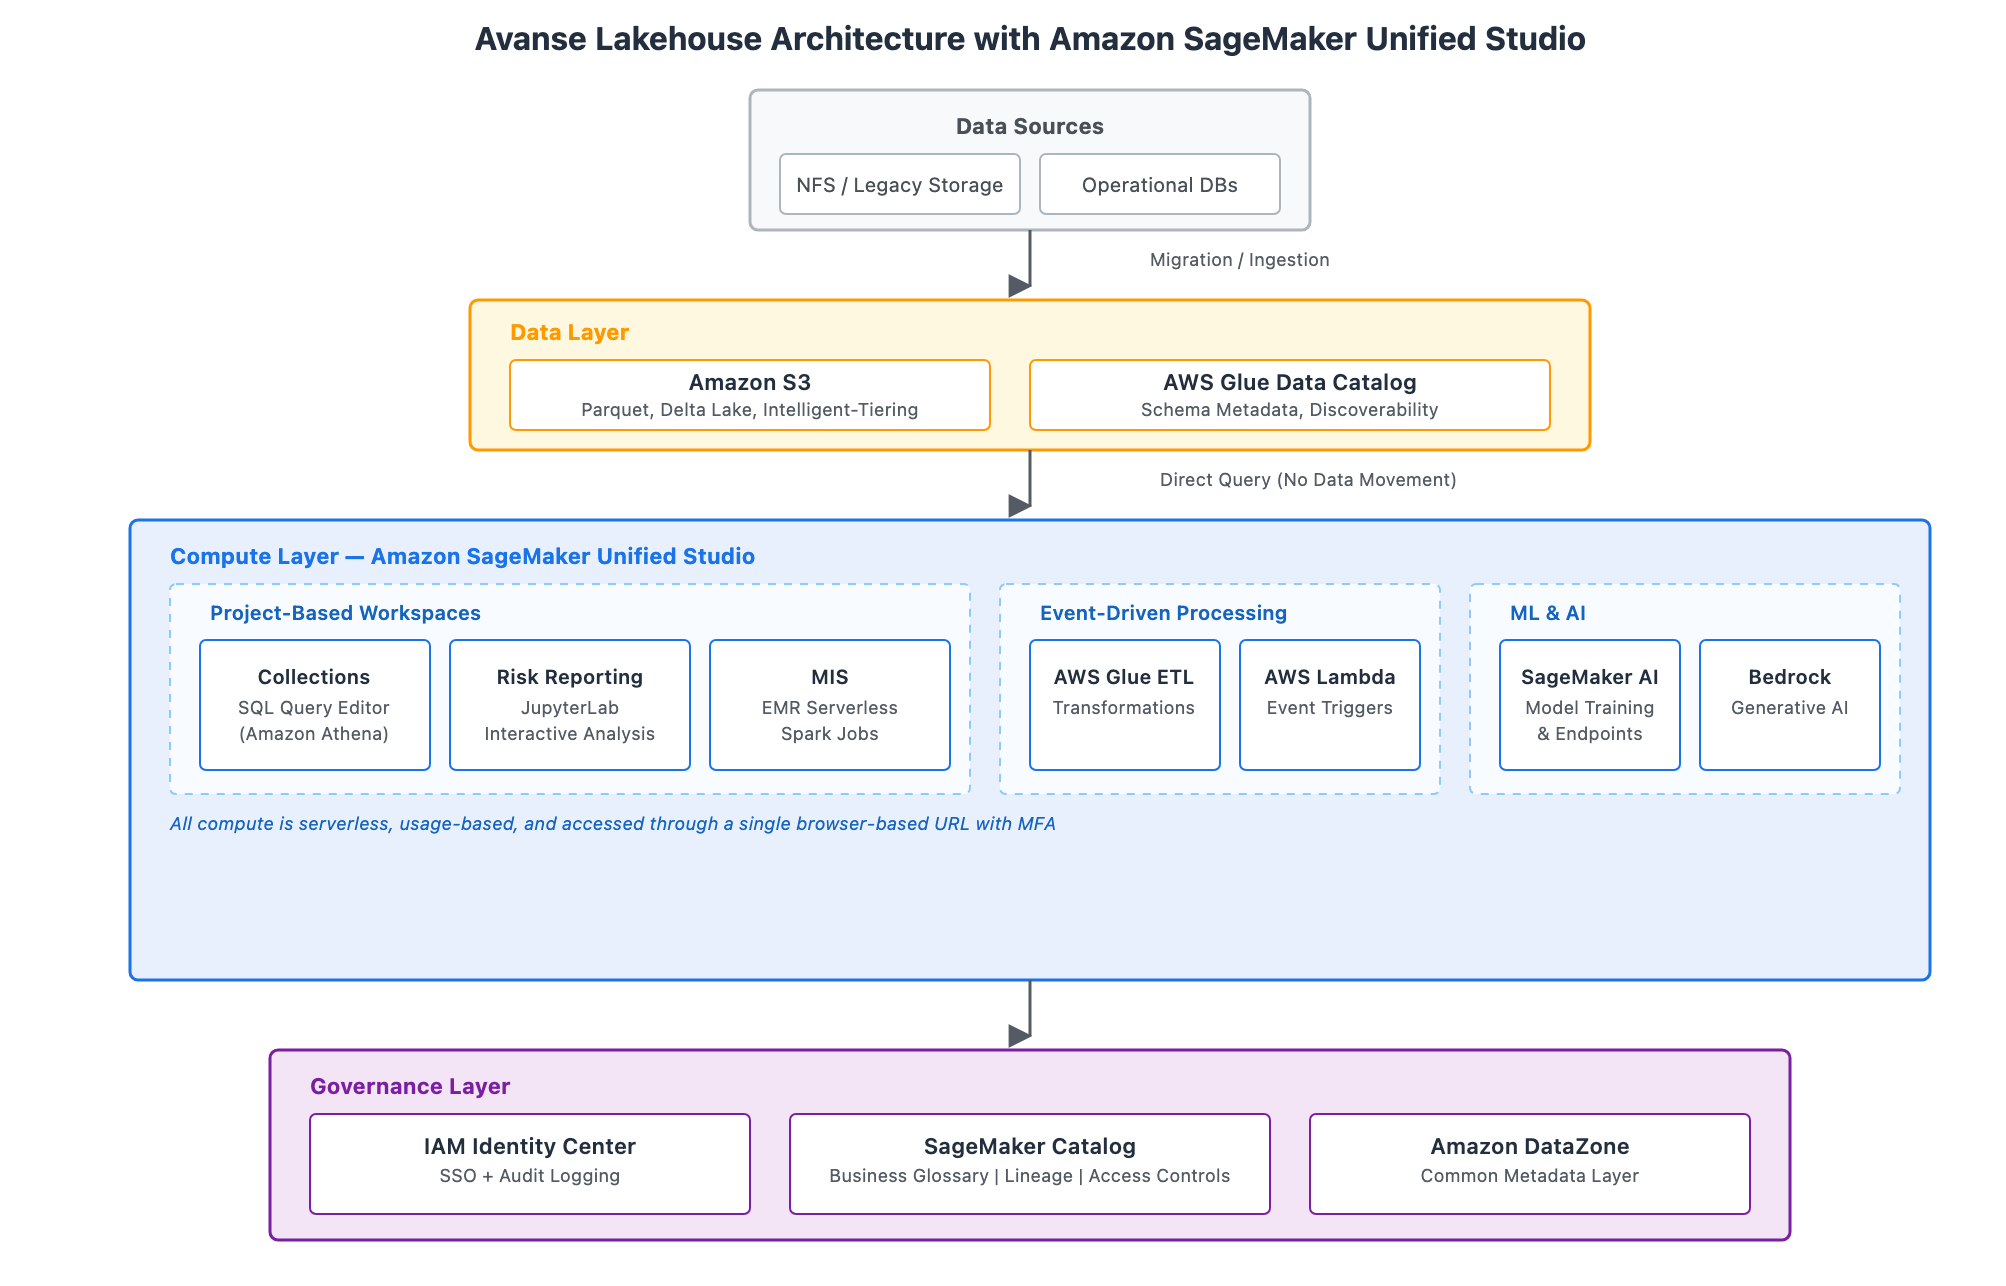
The following diagram illustrates the target architecture. It follows a lakehouse pattern, storing data in open formats on Amazon S3 while maintaining ACID transaction support for the consistency financial regulators expect.

Three-layer lakehouse architecture for Avanse on AWS, showing the data layer with Amazon S3 and AWS Glue Data Catalog, the compute layer with Amazon SageMaker Unified Studio, AWS Glue ETL, AWS Lambda, Amazon EMR Serverless, Amazon SageMaker AI, and Amazon Bedrock, and the governance layer with AWS IAM Identity Center, SageMaker Catalog, and Amazon DataZone

The architecture has three layers:

  1. Data layer – Amazon S3 stores data in open formats (Parquet, Delta Lake) with S3 Intelligent-Tiering for automatic cost optimization. AWS Glue Data Catalog maintains schema metadata, making data discoverable across tools.
  2. Compute layer – Amazon SageMaker Unified Studio provides project-based workspaces organized by business function. Collections uses the built-in SQL Query Editor powered by Athena, Risk Reporting uses JupyterLab for interactive analysis, and MIS runs large-scale Spark jobs through Amazon EMR Serverless. AWS Glue ETL handles data transformations and AWS Lambda provides event-driven triggers for report generation. For machine learning (ML) workloads, Amazon SageMaker AI supports model training and deployment, with Amazon Bedrock available for generative AI capabilities such as enhancing risk narratives.
  3. Governance layer – IAM Identity Center provides SSO and audit logging across workspaces. SageMaker Catalog serves as the business glossary with data lineage tracking and access controls. Amazon DataZone connects components through a common metadata layer.

Migration journey

Avanse followed a five-phase approach. The timelines can be adapted to your environment, but the systematic progression from validation through production deployment is key.

Phase 1: Technical validation (72-hour workshop)

Avanse started with a focused 72-hour workshop using isolated SageMaker environments where developers could experiment without impacting production. Their team tested SQL analytics against existing Athena tables and validated that Python and PySpark could replicate their existing analytics workflows.

The team confirmed that querying data directly in Amazon S3 addressed their synchronization bottleneck entirely. The 4-hour daily data copy was no longer necessary, which validated the migration approach.

Phase 2: Data migration and storage optimization

Avanse migrated datasets from NFS storage and legacy analytics formats into Amazon S3, consolidating the data into a single location. They implemented S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns, optimizing costs without impacting retrieval performance.

They replaced legacy analytics connectors with native Athena workgroups within SageMaker Unified Studio, avoiding data synchronization entirely. Source data remained in Amazon S3, queryable by both Athena SQL and SageMaker notebooks, establishing a single source of truth.

Phase 3: Compute modernization

Avanse moved from a shared analytics server to project-based isolation in SageMaker Unified Studio. Each business function (Risk Reporting, Collections, MIS) received its own project with dedicated compute spaces running JupyterLab. Project-specific IAM execution roles provided access controls and cost allocation per business unit.

A single browser-based URL with multi-factor authentication (MFA) now provides access to SQL analytics using the built-in query editor, ML development in JupyterLab notebooks, and big data processing through Amazon EMR Serverless. This replaced the need for local analytics client installations.

Phase 4: Governance implementation

Avanse deployed SageMaker Catalog as their central business data catalog. Analysts now discover approved datasets through semantic search rather than navigating folder structures or relying on manual documentation. They mapped technical Athena table names to business terms. For example, analysts search for “collection efficiency” and find the relevant tables with descriptions, schemas, and lineage.

Lineage capture traces each metric in risk reports back to source tables, transformations, and intermediate datasets. Every action (notebook execution, SQL query, data access) is tied to IAM Identity Center users, creating the comprehensive audit trail their compliance team needed.

Phase 5: Use case migration

Rather than attempting a big-bang migration, Avanse moved critical workflows one at a time:

Portfolio MIS (Monthly/Fortnightly)
Previously required the daily 4-hour data copy from Amazon S3 into the external analytics application before report generation could begin. Avanse avoided the data synchronization step entirely and now generates MIS reports by querying existing Athena tables directly in Amazon S3. Because the source data was already on AWS, there was no need to involve the external application for this activity. Report generation dropped from hours to under 30 minutes.
Collection Efficiency and Bounce Calculation
Ported complex legacy analytics procedures for calculating metrics like collection efficiency and bounce rates to event-driven processing using AWS Glue ETL, AWS Lambda, and PySpark jobs for high-volume data aggregation. The serverless execution model charges only for compute time consumed.
EDW Risk Reporting
Large-scale regulatory joins of Enterprise Data Warehouse assets previously ran as legacy scheduled procedures. These now run as SQL queries in the SageMaker Unified Studio query editor, where analysts execute them on-demand or schedule them through Athena workgroups. The distributed query engine handles complex multi-table joins spanning millions of rows.
Scorecard Generation
Model building shifted from the external analytics application to SageMaker AI workflows. Data scientists use JupyterLab with Python libraries and deploy models directly to SageMaker endpoints, avoiding data movement between separate environments.

Overcoming technical challenges

One technical challenge was code migration. Avanse’s analytics code base contained years of accumulated proprietary scripts and procedures. Direct line-by-line translation was not practical. Instead, they took a pragmatic approach: basic data transformations moved to SQL in Athena, complex business logic was rewritten in PySpark for scalability, and statistical procedures were replaced with Python libraries like pandas and scikit-learn. The approach was to focus on what the code accomplishes, then implement it using cloud-native patterns.

The other technical challenge was performance validation. The team needed to confirm that querying data in Amazon S3 would deliver acceptable performance compared to the external analytics application’s in-memory processing. Queries against Parquet-formatted data in Amazon S3 using Athena delivered comparable performance for standard reporting workloads, while avoiding the 4-hour daily data synchronization step entirely. For large-scale regulatory joins spanning millions of rows, Amazon EMR Serverless provided distributed Spark processing that completed in minutes rather than the hours required in the external application.

Key outcomes

Area Result
Licensing costs Avoided external analytics application fees entirely
Storage costs Reduced through S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns
Report generation From over 4 hours (including data synchronization from Amazon S3 to the external analytics application) to under 30 minutes with direct Amazon S3 querying
Compliance audits From weeks of manual investigation to days with automated lineage reports
Compute costs Usage-based serverless model replaced always-on external analytics infrastructure
Collaboration Unified browser-based environment for data scientists, analysts, and engineers

“By adopting SageMaker Unified Studio, we as the Data Team eliminated legacy licensing costs, reduced storage and compute expenses with a serverless, usage-based model, and accelerated our periodic report generation. At the same time, we transformed compliance and collaboration by cutting audit timelines while unifying our teams in a single, efficient data environment.” – Komal Thakkar, AVP – Lead, Data Engineering, Avanse Financial Services

Best practices

Based on their experience, Avanse recommends:

  • Start with a workshop. Validate your specific use cases in a 72-hour technical validation before committing to full migration.
  • Migrate use cases, not code. Focus on what your analytics accomplish, then implement using cloud-native patterns rather than translating legacy scripts line by line.
  • Invest in governance early. Implement the data catalog and lineage tracking from day one.
  • Embrace project-based isolation. Organize around business functions for clear cost allocation and security boundaries.
  • Document business logic. Use migration as an opportunity to capture undocumented knowledge in the business glossary and dataset descriptions.

Conclusion

Avanse’s migration from an external analytics application to Amazon SageMaker Unified Studio consolidated their analytics stack into a single integrated environment on AWS. By querying data directly in Amazon S3 instead of copying it into the external application, they alleviated their biggest operational bottleneck. Project-based isolation replaced a shared server model, giving each business unit independent compute and clear cost visibility. And centralized governance through SageMaker Catalog and IAM Identity Center gave their compliance team the audit trails they had been missing.

The serverless, usage-based model means Avanse no longer pays for idle capacity. The lakehouse architecture supports new analytics patterns as they emerge, and native integration with AWS services, including generative AI through Amazon Bedrock, positions them to adopt new capabilities as their needs evolve.

Next steps

Start your analytics modernization journey by scheduling a 72-hour technical validation workshop. Contact your AWS account team to discuss your migration approach.

For more information, see:

Automating IT support with AI: How Nexthink uses OpenSearch Service to power self-service issue resolution

Post Syndicated from Rafael Ribeiro, Moe Haidar original https://aws.amazon.com/blogs/big-data/automating-it-support-with-ai-how-nexthink-uses-opensearch-service-to-power-self-service-issue-resolution/

This is a guest post by Rafael Ribeiro and Moe Haidar, at Nexthink, in partnership with AWS.

Nexthink is the leader in digital employee experience, helping enterprises improve how employees interact with technology in the workplace. The company gives IT teams real-time visibility into endpoint performance, application usage, and employee sentiment across millions of devices worldwide.

At the heart of Nexthink’s innovation is Spark, an autonomous artificial intelligence (AI) agent that automates IT support. Spark resolves IT issues for employees, from troubleshooting application crashes to resetting configurations and running remediation scripts. Rather than routing tickets or providing scripted responses, the agent takes direct action, achieving a 77% resolution rate at first contact without human escalation.

Spark operates at enterprise scale, deployed across 12 AWS Regions to serve global customers with low-latency responses.

In this post, we explore how Nexthink combined Amazon OpenSearch Service vector search, Amazon Bedrock, and infrastructure as code to power the Spark agent’s retrieval layer.

The challenge: Why vector search for AI agents?

For an AI agent to autonomously resolve IT issues, it must quickly retrieve the most relevant context from a vast knowledge base. Traditional keyword search falls short because:

  • Semantic understanding matters: An employee asking “my laptop is running slow” should match articles about “system performance optimization” even without exact keyword overlap.
  • Accurate retrieval drives correct outcomes: The quality of an AI agent’s response is only as good as the context it retrieves. When the agent pulls the right documentation, scripts, and historical resolutions, it produces accurate, safe actions. When retrieval is imprecise, the consequences can be severe. An agent acting on the wrong context could run destructive commands like rm -rf *, wipe critical data, or apply an incorrect fix that escalates the problem. Accurate vector search is the guardrail that keeps autonomous agents grounded in verified, relevant knowledge.
  • Speed is critical: Enterprise users expect near-instant responses, so retrieval must run in sub-second time across millions of documents.

This led Nexthink to implement Amazon OpenSearch Service with vector search capabilities, using Amazon Titan Text Embeddings V2 through Amazon Bedrock for embedding generation. With this architecture, Spark performs semantic search across all knowledge sources, retrieving contextually relevant information that drives accurate, autonomous issue resolution.

High-level architecture

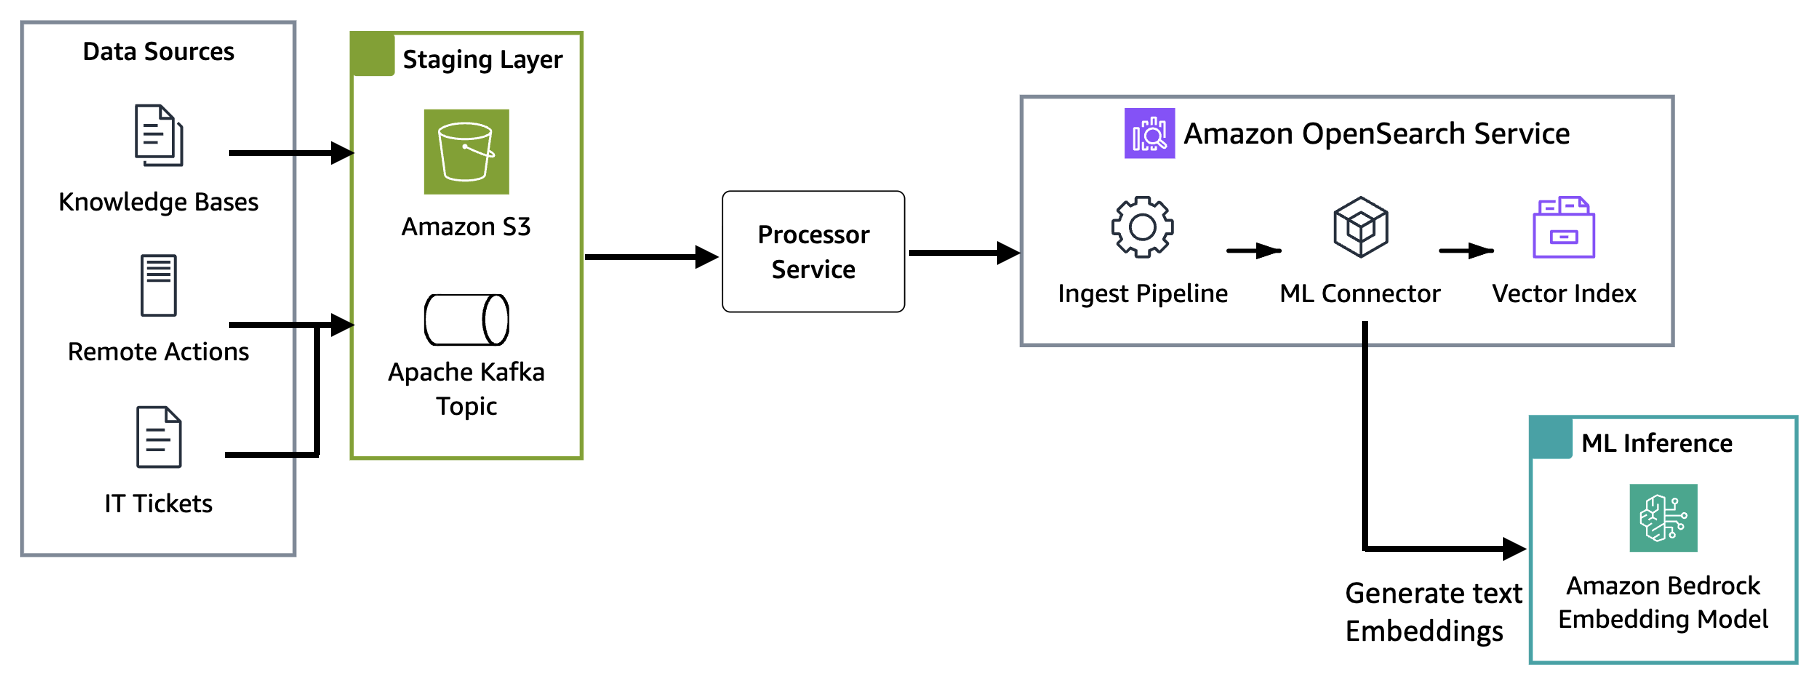
The following diagram illustrates the high-level architecture of Nexthink’s Spark agent implementation with Amazon OpenSearch Service.

High-level architecture of Nexthink’s Spark AI agent, showing Amazon Elastic Kubernetes Service hosting the agent, Amazon OpenSearch Service as the vector store, and Amazon Bedrock providing the embedding model

Architecture components

Amazon Elastic Kubernetes Service (Amazon EKS) hosts the Spark agent, which interprets user queries, retrieves relevant context, and runs autonomous resolutions. With container orchestration, the agent scales horizontally across Nexthink’s 12 AWS Regions while maintaining consistent response times. The agent communicates with Amazon OpenSearch Service to perform semantic searches, retrieving the most contextually relevant documentation and automation scripts for each user’s issue.

Amazon OpenSearch Service functions as the central vector store, providing the k-Nearest Neighbors (k-NN) capabilities required for semantic search. OpenSearch Service stores document embeddings (dense vector representations of text content) alongside traditional metadata fields. When the AI agent submits a query, OpenSearch Service performs approximate nearest neighbor (ANN) searches to find documents with semantically similar embeddings, even when exact keywords don’t match. This vector search capability, combined with the proven scalability and managed infrastructure of OpenSearch Service, makes it well suited for AI agent architectures that require fast, accurate context retrieval.

Amazon Bedrock provides the foundation models used to generate text embeddings. Nexthink uses Amazon Titan Text Embeddings V2, hosted on Amazon Bedrock, to convert both documents and queries into dense vector representations. OpenSearch Service integrates natively with Amazon Bedrock through the OpenSearch ML Connector, which handles embedding generation at both index and query time.

Data ingestion pipeline

A critical component of any AI agent architecture is the data ingestion pipeline. This mechanism transforms raw documents into searchable, semantically indexed content in OpenSearch Service. For Spark, the pipeline must handle diverse data sources while automatically generating vector embeddings for semantic search.

Step 1: Staging and preprocessing layer

Staging layer in Amazon S3

Knowledge bases (KBs) are staged in Amazon Simple Storage Service (Amazon S3) before being processed through the ingestion pipeline. Amazon S3 provides durable storage, versioning capabilities, and integration with OpenSearch Service ingestion mechanisms. When documentation updates occur, new versions are uploaded to Amazon S3, which triggers the ingestion pipeline to reprocess and re-embed the content.

Event-driven streaming with Apache Kafka

IT tickets, agent interactions, and remote actions are processed through Apache Kafka for reliable message delivery during traffic spikes. Its consumer group model lets the ingestion pipeline scale horizontally based on event volume.

Step 2: Embedding generation during indexing time

Nexthink uses ingest pipelines inside OpenSearch Service to process the data at ingestion time, including generating text embeddings. When documents are sent to OpenSearch Service, the text_embedding processor inside the ingest pipeline automatically invokes the machine learning (ML) Connector to generate embeddings.

The ML Connector is the OpenSearch Service built-in framework for integrating external ML services. It handles request signing between OpenSearch Service and Amazon Bedrock, parses the Amazon Bedrock response to extract embeddings, maps them to index fields, and manages retries on failure. This eliminated the need for custom integration code and accelerated Nexthink’s time to market.

The following ingestion pipeline configuration demonstrates how to configure the text_embedding processor.

{
  "description": "Embedding ingestion pipeline for Spark AI Agent",
  "processors": [
    {
      "text_embedding": {
        "model_id": "<bedrock-connector-model-id>",
        "field_map": {
          "content": "content_embedding"
        }
      }
    }
  ]
}

In this configuration:

  • model_id: References the registered ML model connected to Amazon Bedrock.
  • field_map: Maps the source text field (content) to the target embedding field (content_embedding).

Step 3: Embeddings and data structure in OpenSearch Service

Nexthink stores embeddings alongside textual and metadata information in their k-NN index. For the vector field, they use Hierarchical Navigable Small World (HNSW) with the Lucene engine, as shown in the following example.

...
"content_embedding": {
  "type": "knn_vector",
  "dimension": 1024,
  "method": {
    "name": "hnsw",
    "space_type": "innerproduct",
    "engine": "lucene"
  }
},
"document_type": {
  "type": "keyword"
},
"tenant_id": {
  "type": "keyword"
}
...

In this configuration:

Multi-tenant search and retrieval

Enterprise AI agent deployments must address a critical challenge: making sure that users only access data they’re authorized to see. For Nexthink, serving multiple enterprise customers from a shared infrastructure requires robust multi-tenant security. Each customer’s knowledge base, automation scripts, and support tickets must remain isolated while the shared vector index continues to perform well.

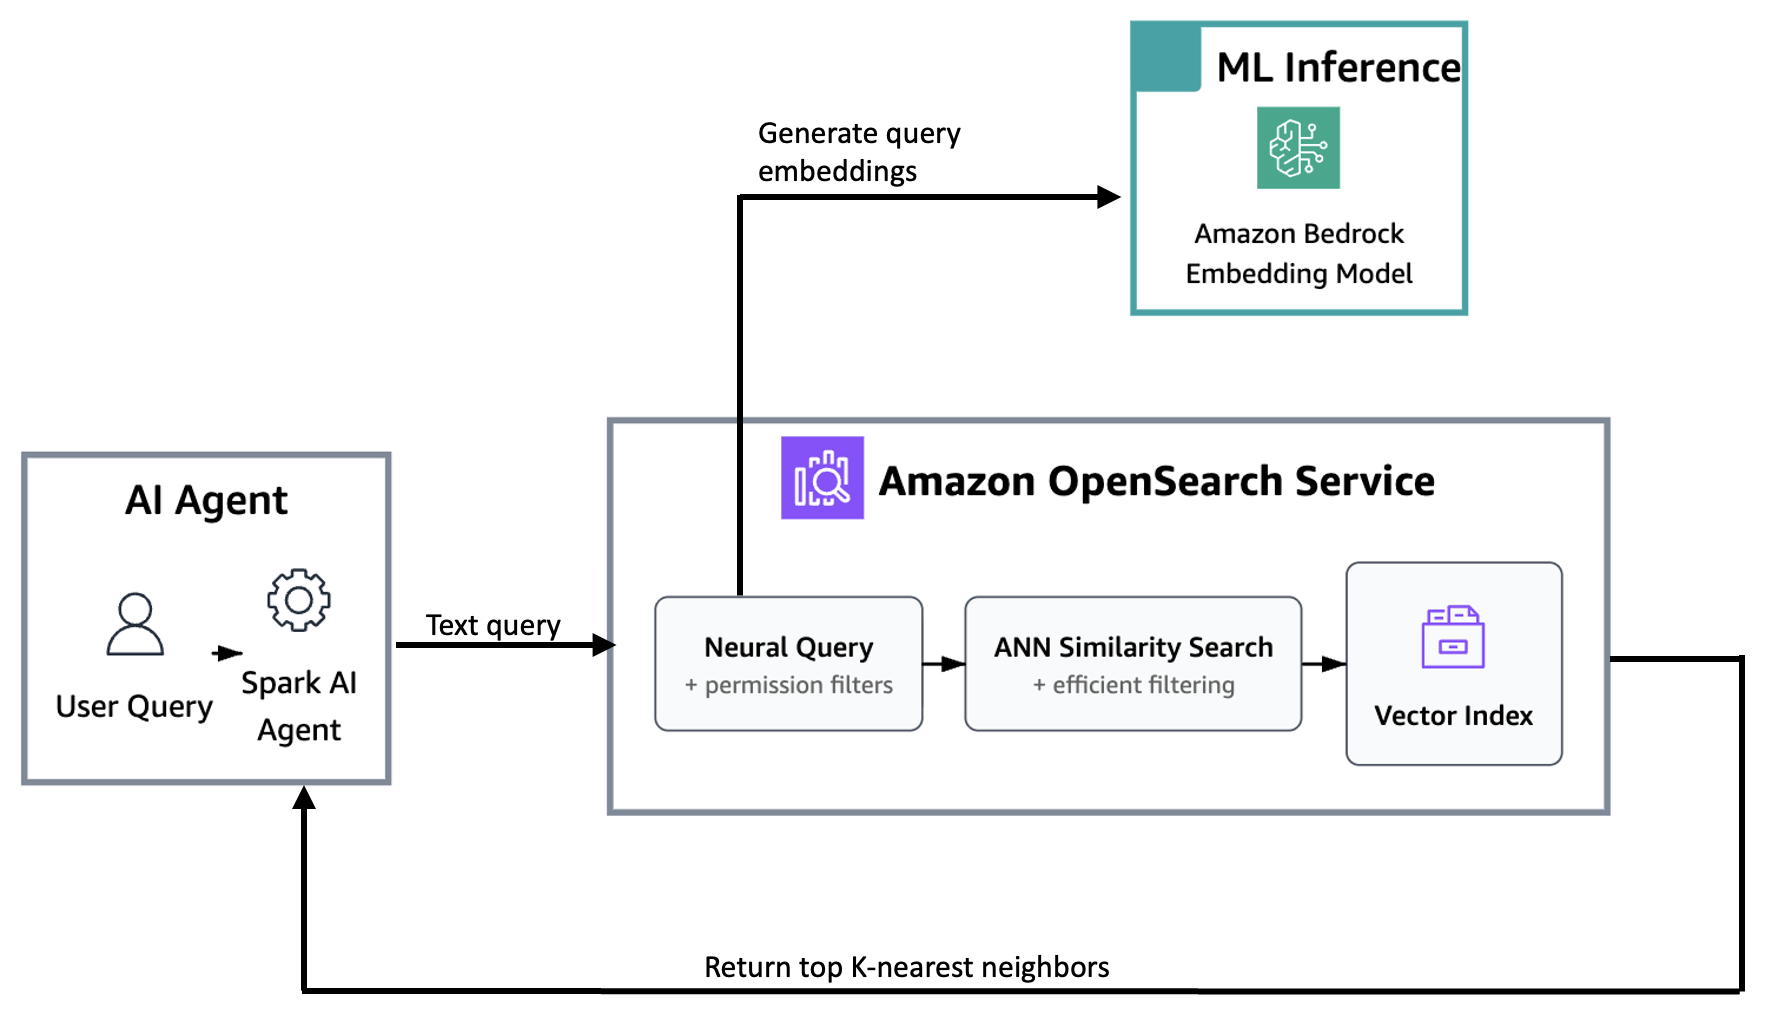
The following diagram illustrates the search flow from user query to ranked results.

Search flow showing how a user query travels through the Spark agent, OpenSearch Service neural search, the ML Connector to Amazon Bedrock for embedding, and tenant-filtered k-NN retrieval to produce ranked results

Tenant management

Nexthink stores information about each tenant inside the tenant_id field. This design lets permission filters run efficiently alongside vector similarity searches. Additionally, Nexthink stores the tenant_id as a keyword type in the index mapping shared previously, so that filtering runs without the overhead of text analysis. Instead of pre-filtering with k-NN queries through a score script filter, the OpenSearch engine uses an intelligent decision-based approach for k-NN filtering called efficient filtering.

Neural query example with efficient filtering

OpenSearch’s neural search simplifies vector search by handling embedding generation as part of the query itself. Instead of requiring the application to call an embedding model separately and then submit a raw k-NN query with a vector, a neural query accepts plain text and uses the registered ML Connector to generate the embedding on the fly. As a result, the Spark agent can send natural-language queries directly to OpenSearch Service without any client-side embedding logic.

The following query demonstrates how Nexthink combines neural search with tenant isolation through efficient filtering in OpenSearch Service.

{
  "query": {
    "bool": {
      "must": [
        {
          "neural": {
            "content_embedding": {
              "query_text": "laptop running slow",
              "model_id": "<bedrock-connector-model-id>",
              "k": 50
            }
          }
        }
      ],
      "filter": [
        {
          "term": {
            "tenant_id": "customer-123"
          }
        }
      ]
    }
  }
}

In this query structure:

  • bool.must: Contains the neural search clause that performs semantic matching against document embeddings.
  • bool.filter: Applies the tenant isolation constraint, so that only documents belonging to customer-123 are returned.

Nexthink’s contribution to the technical community

A key principle in Nexthink’s architecture is treating infrastructure as code. With deployments spanning 12 AWS Regions, manual provisioning would be error-prone and time-consuming. Therefore, Nexthink uses several infrastructure as code (IaC) technologies, including Terraform, to provision resources.

Although the Terraform provider supports core OpenSearch Service resources like indices and index templates, it lacked support for some of the ML Commons resources required to integrate Amazon Bedrock:

  • ML Connectors: Required to establish connections to external ML services like Amazon Bedrock.
  • ML Model Groups: Needed to organize and manage related models.
  • ML Models: Required to register models that use the connectors.

Without these resources, Nexthink initially relied on workarounds using local-exec provisioners and null_resource blocks to call the OpenSearch Service API directly. This approach was fragile, difficult to maintain, and didn’t integrate well with Terraform’s state management.

Contributing back

Rather than maintaining a private fork indefinitely, Nexthink chose to contribute their custom Terraform resources back to the OpenSearch Project community. This decision aligned with their engineering values to help other organizations implement similar architectures and contribute to the broader community.

Open source contribution links

The Terraform provider contributions are being added to the official OpenSearch project repository:

  • Pull Request: Add support for ML Connector, ML Model Group, and ML Model resources #280.
  • Feature Request: Contribution – Support for ML resources #281.

These contributions let any organization provision OpenSearch Service ML resources with Terraform, which streamlines the deployment of AI agent architectures that integrate with Amazon Bedrock or other ML services.

Conclusion

Nexthink’s implementation of Amazon OpenSearch Service for the Spark agent demonstrates how vector search capabilities can power autonomous IT support at enterprise scale. By combining semantic search with multi-tenant security and infrastructure as code practices, Nexthink achieved a 77% resolution rate at first contact, so that employees can resolve IT issues without human escalation.

Get started

Ready to build your own AI agent with vector search capabilities? Here are your next steps:

  1. Explore Amazon OpenSearch Service vector search features in the OpenSearch Service documentation.
  2. Configure ML Connectors for Amazon Bedrock using the ML Commons plugin guide.
  3. Automate with Terraform using the contributed resources in the terraform-provider-opensearch repository.

The combination of Amazon OpenSearch Service, Amazon Bedrock, and infrastructure as code practices provides a foundation for building intelligent, context-aware AI agents that deliver business value.


About the authors

Rafael Ribeiro

Rafael Ribeiro

Rafael is a Software Engineer at Nexthink, focusing on infrastructure and DevOps for AI teams.

Moe Haidar

Moe Haidar is Head of Agentic AI and Engineering at Nexthink, where he leads AI architecture and strategy alongside the development of Spark, the company’s autonomous personal IT agent that resolves employee issues at scale.

Hajer Bouafif

Hajer Bouafif

Hajer is an Analytics Specialist Solutions Architect at Amazon Web Services. She focuses on Amazon OpenSearch Service and helps customers design and build well-architected analytics workloads in diverse industries. Hajer enjoys spending time outdoors and discovering new cultures.

Luca Perrozzi

Luca Perrozzi

Luca is a Solutions Architect at AWS, based in Switzerland. He focuses on innovation topics at AWS, especially in the area of Artificial Intelligence. Luca holds a PhD in particle physics and has 15 years of hands-on experience as a research scientist and software engineer.

AWS Weekly Roundup: NY Summit recap, Local Zone in Hanoi, Grok 4.3 in Bedrock, price reductions, and more (June 22, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-ny-summit-recap-local-zone-in-hanoi-grok-4-3-in-bedrock-price-reductions-and-more-june-22-2026/

Last week AWS Summit New York City brought together thousands of customers, partners, and builders for a free, one-day event showcasing the latest in cloud and AI innovation. Dr. Swami Sivasubramanian, VP of Agentic AI at AWS unveiled a stack of AI launches in his keynote, all built around one thesis: agents that compound value over time.

  • Agents for working – You can launch autonomous agents and access a smarter activity feed with new Amazon Quick features, which now let you create and run multi-step agents directly in the desktop app and consolidates email, Slack, calendar, and tasks into a single prioritized view with personalized rules.
  • Agents for securing – You can shift from reactive to proactive security with AWS Continuum, a new AI-native security service that reasons, validates, and acts at machine speed across the full code vulnerability lifecycle. AWS Security Agent (now part of AWS Continuum) adds new features: threat modeling; pull request code scanning with remediation across major Git platforms; and IDE integrations via Kiro power, Claude Code plugin, and MCP.
  • Agents for building – You can write, ship, and modernize code in one continuous loop with Kiro, AWS DevOps Agent, and AWS Transform. Kiro introduces a native iOS app; AWS DevOps Agent adds release management capabilities to assess code changes before production; and AWS Transform continuous modernization reduces tech debt autonomously.
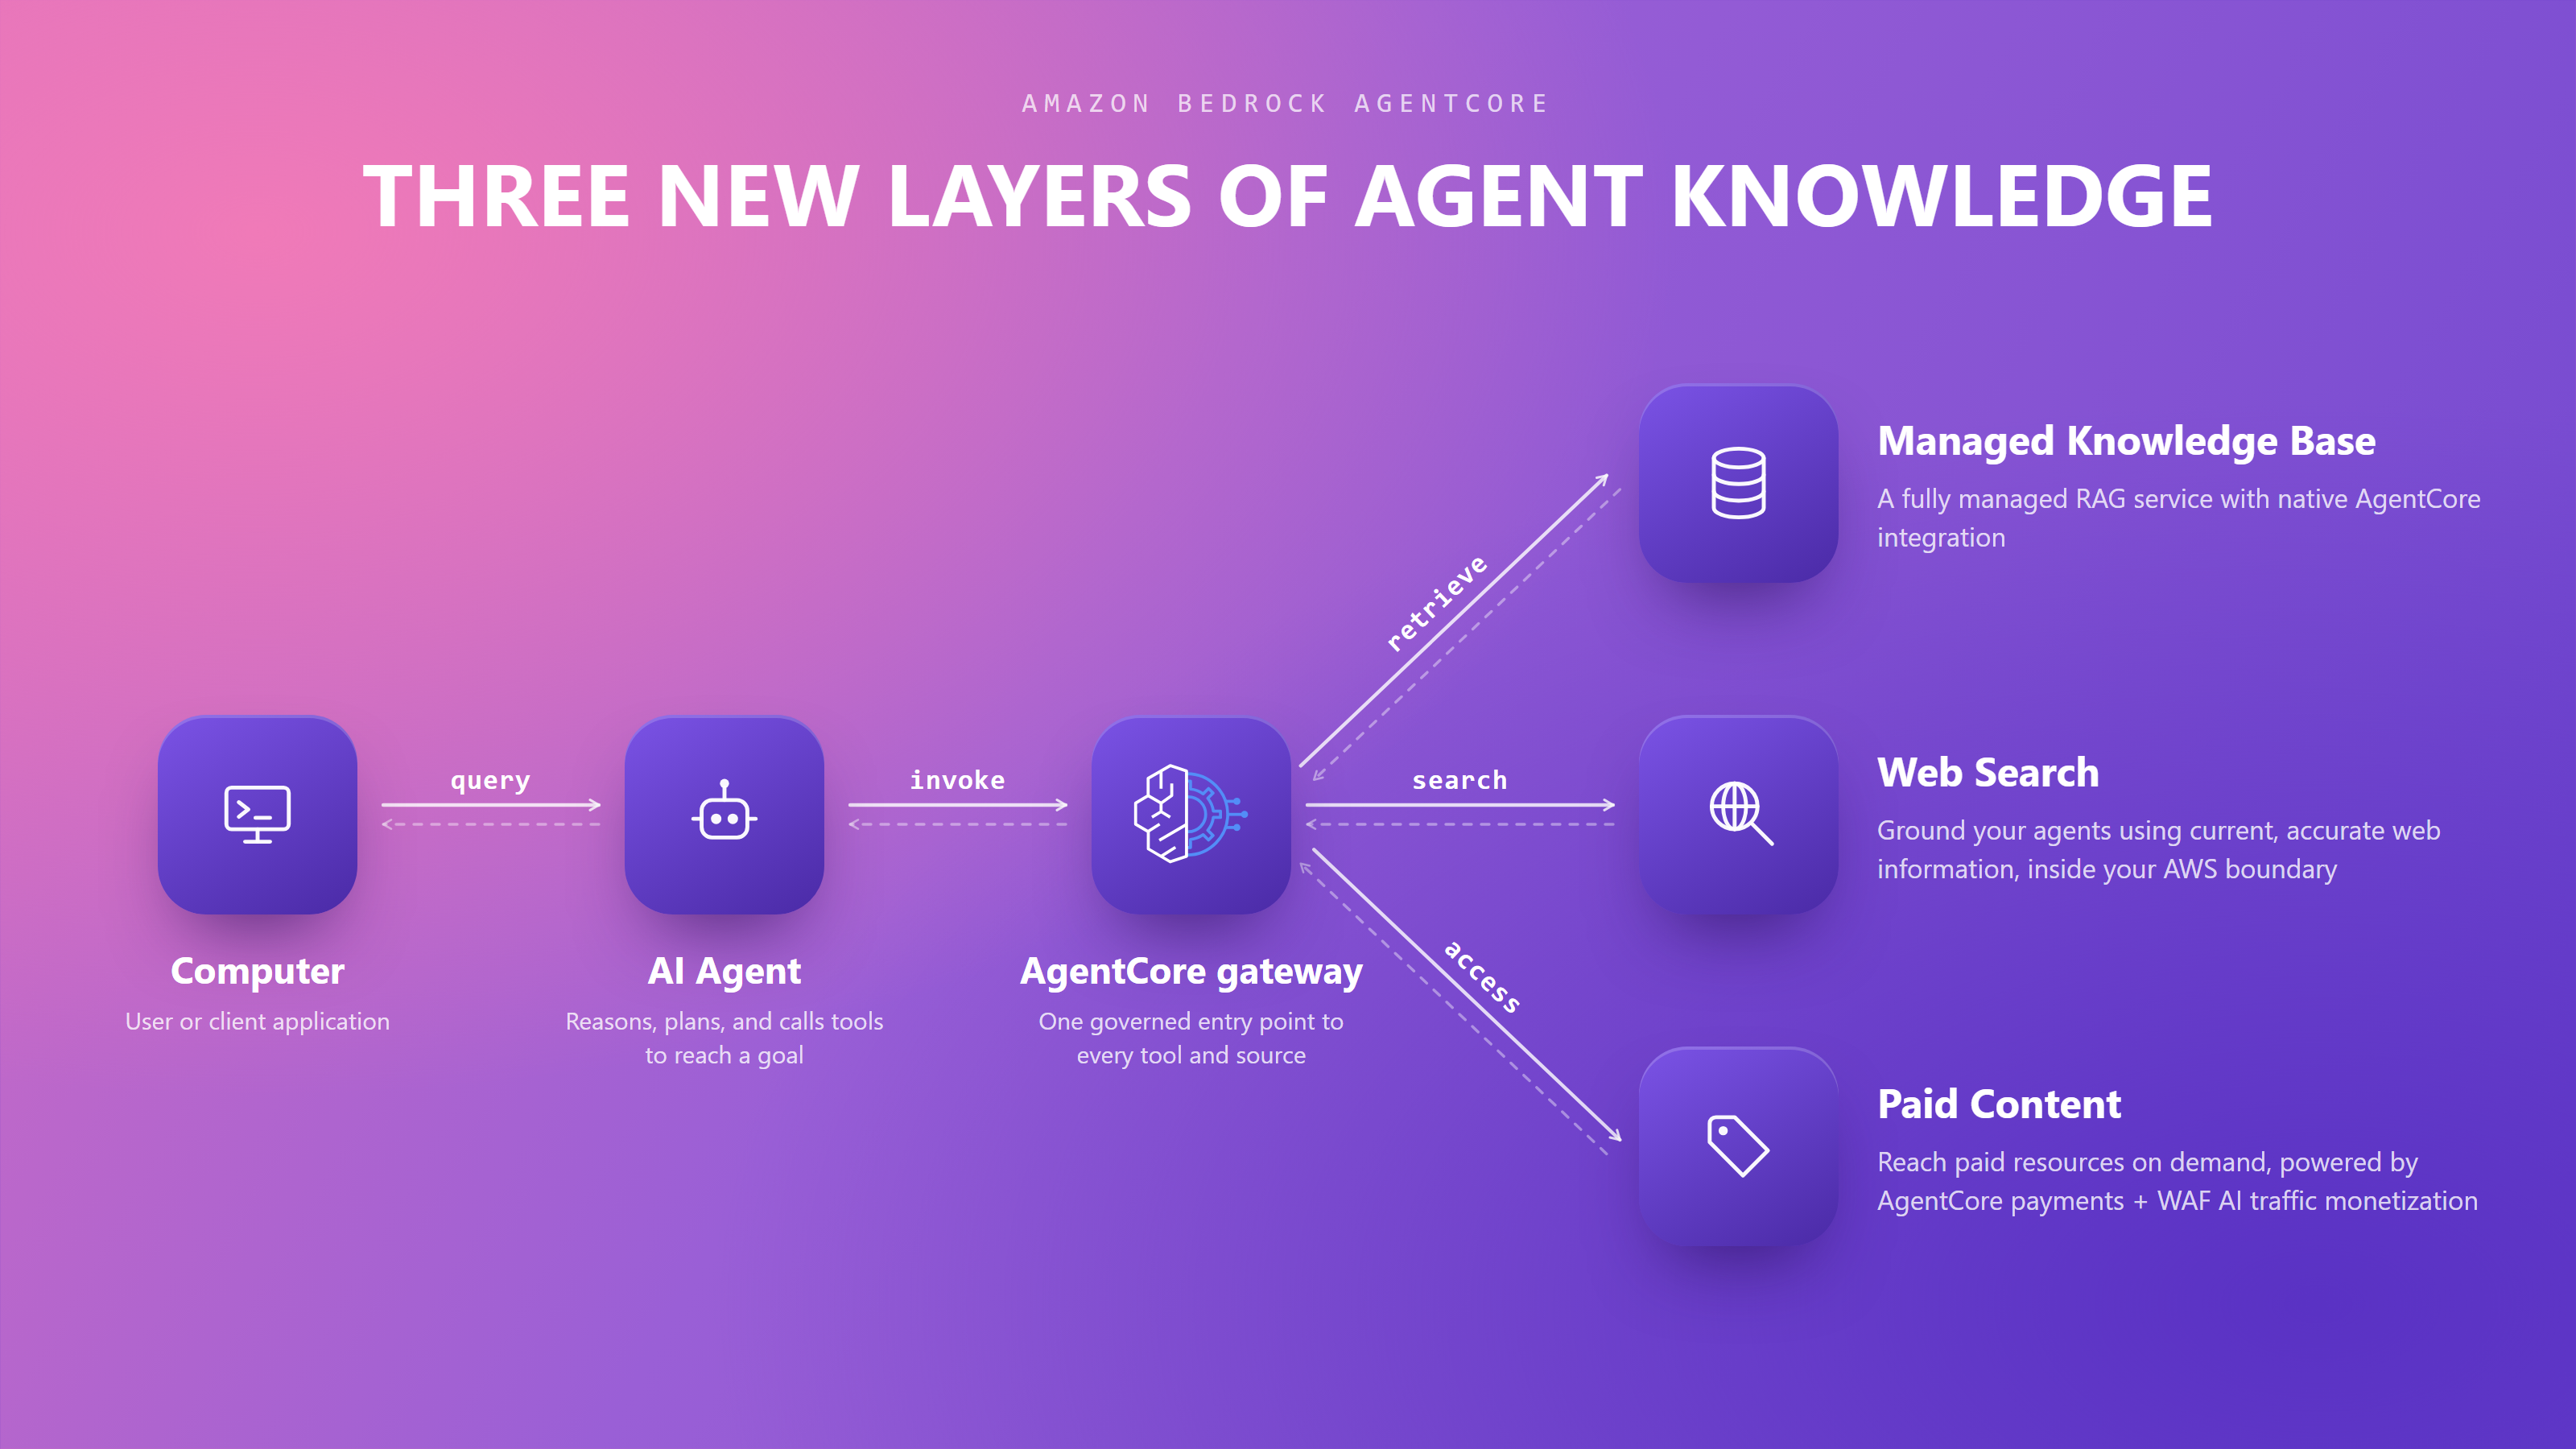
  • Agents customers create – You can go from agent idea to production in minutes with Amazon Bedrock AgentCore, which now includes a GA harness for infrastructure and orchestration, Web Search, Managed Knowledge Base, policy integrations with Guardrails, and the new AWS Context service for mapping organizational data relationships.

To learn more, visit the Summit recap from our top announcements blog post and Amazon News post.

Last week’s launches
Here are last week’s launches that caught my attention:

  • AWS Local Zone in Hanoi, Vietnam  —This new Local Zone is one of the first AWS Local Zones in the Asia Pacific with support for Amazon S3 and Amazon EBS Local Snapshots, enabling customers to meet data residency requirements by storing and backing up data locally. To get started, enable the Hanoi Local Zone (ap-southeast-1-han-1a) from the Regions and Zones tab in the AWS Global View or by using the ModifyAvailabilityZoneGroup API.
  • AWS Blocks, an open-source TypeScript framework for application developers (preview) — AWS Blocks runs a fully functional local environment with Postgres, authentication, and real-time messaging, no AWS account required. When you’re ready to deploy, the same application code runs on production AWS services with zero changes, and you can drop into AWS CDK at any point for direct resource configuration.
  • Grok 4.3 from xAI in Amazon Bedrock —You can use the Grok 4.3 model on Amazon Bedrock, giving you even more choice as you build generative AI applications across reasoning, agentic, and enterprise workflows. Grok 4.3 runs on a new inference engine in Bedrock designed for price performance, with support for tool calling, structured output, and response streaming.
  • Amazon S3 annotations: attach rich, queryable context directly to your objects — Amazon S3 now lets you attach up to 1 GB of rich, mutable, and queryable context directly to your objects using annotations, purpose-built for AI agents and autonomous workflows that need to discover, understand, and act on data at scale without maintaining separate metadata systems.
  • Amazon ECS announces faster service auto scaling — Amazon ECS service auto scaling now detects and responds to load changes faster with support for high resolution (20-second) metrics and metric publishing optimizations. In AWS benchmarking tests, time to trigger scale-out improved from 363 seconds to 86 seconds (76% faster), and total time to scale and provision new tasks improved from 386 seconds to 109 seconds (72% faster).
  • Amazon EC2 G7 instances accelerated by NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs — AWS is the first major cloud provider to support NVIDIA RTX PRO 4500 Blackwell Server Edition GPUs. G7 instances are accelerated by these GPUs with custom sixth-generation Intel Xeon Scalable processors, delivering up to 4.6x AI inference performance and up to 2.1x graphics performance compared to G6 instances.
  • Strands Agents introduces new capabilities — Strands is an open source toolkit for building production agents. You can now use better context management in Harness SDK, a new isolated execution environment with Strands Shell, and chaos testing and red teaming in Strands Evals.
  • AWS Management Console Private Access – You can access the AWS Console from VPCs without internet connectivity, allowing enterprises to manage their AWS infrastructure through the console while maintaining strict network security controls in air-gapped environments.
  • AWS Marketplace Storefront is now generally available – AWS Partners can create and deploy their own branded catalog of solutions and services on their website or application in hours. Channel Partners and Independent Software Vendors can now simplify how they manage their cloud marketplace business and make it easier for customers to discover and purchase their solutions from AWS Marketplace.
  • Palo Alto Networks (PANW) Advanced DNS Security on Amazon Route 53 Resolver DNS Firewall (preview) – You can now enforce DNS threat protections from Palo Alto Networks directly on Route 53 DNS Firewall rules, without deploying separate firewalls or modifying VPC configurations — by subscribing to PANW from the DNS Firewall console through the embedded AWS Marketplace widget.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Price reductions 
AWS continues to look for ways to increase performance and lower prices for our customers. I noticed a few such efforts last week, so I’d like to share them:

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Top announcements of the AWS Summit in New York, 2026

Post Syndicated from AWS News Blog Team original https://aws.amazon.com/blogs/aws/top-announcements-of-the-aws-summit-in-new-york-2026/

Today at the AWS Summit in New York City, Swami Sivasubramanian, AWS VP of Agentic AI, provided the day’s keynote. Here’s our roundup of the biggest announcements from the event:

New in Amazon Bedrock AgentCore
We’re introducing new capabilities on Amazon Bedrock AgentCore: connecting AI agents to organizational, web, and paid knowledge, helping teams find and fix what’s going wrong in production, and enforcing controls that scale as agents grow more capable.

Together, these capabilities help you build more capable agents faster, govern those agents with controls that scale, and improve them continuously. To learn more, read our blog post covering all the new features.

New in AI-based security tools

New in building AI-based applications 

  • Introducing Kiro for iOS — Kiro introduces a native iOS app, available in a gated preview, built for real engineering work that gives developers a new surface to kick off, monitor, steer, and interact with their Kiro sessions directly from their phone. That means you can now start sessions, check back when they’re done, review diffs, and approve changes all while staying connected to your work with no laptop running.
  • AWS DevOps Agent adds release management capabilities to assess code changes before production — You can use a new release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments.
  • Proactively reduce tech debt autonomously with AWS Transform – continuous modernization — You can use continuous analysis (preview) to automatically scan your code repositories against configurable baselines and generates findings in hours, not weeks. Once you’ve identified and prioritized findings, you can configure autonomous remediations that generate pull requests for affected repositories automatically.

In addition to the keynote announcements, we have other important launches this week:

Announcing Web Search on Amazon Bedrock AgentCore: Ground your AI agents in current, accurate web knowledge

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-web-search-on-amazon-bedrock-agentcore-ground-your-ai-agents-in-current-accurate-web-knowledge/

Today, we’re announcing the general availability of Web Search on Amazon Bedrock AgentCore, a fully managed tool that enables agents to ground responses in current, cited web knowledge with zero data egress from customer’s secured AWS environment.

Web Search uses a built-in connector target on Bedrock AgentCore Gateway using the Model Context Protocol (MCP). Your agent sends a natural-language query, and Web Search returns most relevant snippets, source URLs, titles, and publication dates that the model can reason over to produce a grounded response.

It is built on Amazon’s search infrastructure, informed by years of experience powering agentic search experiences across Alexa+, Amazon Quick, and Kiro. It uses a multi-source grounding approach that combines Amazon’s web index with structured knowledge graph data. Beyond standard web results, this gives agents access to Amazon Knowledge Graph with verified facts, helping them retrieve more relevant and accurate responses than traditional web search alone.

With this launch, you can focus on building agents instead of manually adding web search to agents on Bedrock AgentCore and managing its infrastructure. Your AI agent looks at user question, retrieves the latest facts, and then takes any necessary action grounded in current developments beyond a model’s training data. You can also meet enterprise governance policies without sending user prompts and retrieval queries to external search API providers outside of AWS.

Web Search on Bedrock AgentCore in action
To get started, create the Bedrock AgentCore Gateway with Web Search tool target in the Bedrock AgentCore console. When the Gateway URL is created, you can interact with API call, Command Line Interface (CLI), or MCP Inspector.

To add Web Search tool target when creating the Gateway, choose MCP target as a target protocol and Connectors as a target type. You can select the Web Search tool as a preconfigured target to retrieve most relevant web search results including links, snippets, and metadata.

After creating your gateway, you can find the Web Search tool target on the detail page of your gateway. You can also add a new Web Search tool target to an existing gateway.

To interact with Web Search tool, use the sample invocation code in the View invocation code section. You can use code snippets through Python codes with API requests, MCP Python SDK, Strands MCP Client, and MCP Inspector.

For example, you can interact with the MCP Inspector, an interactive developer tool for testing and debugging MCP servers. When you connect to the MCP server through the Gateway resource URL, you will find a Web Search tool for each connector target on the Gateway. Enter input the web search query and choose Run Tool to get the results.

To learn more about how to use Web Search on Bedrock AgentCore, visit the Bedrock AgentCore Gateway documentation.

Customer voices
Some of our customers had early access to this new feature. This is what they shared with us:

Benchling helps scientists accelerate R&D, making it easy to centralize scientific data, collaborate across teams, and access insights. Nicholas Larus-Stone, Head of AI Agents at Benchling shared “Scientists using Benchling AI can now ask about a target they’re actively working on and get answers grounded in both their institutional data in Benchling and published literature. The result is more complete science, and hypothesis generation done right. Because we’re using the Web Search tool on Amazon Bedrock AgentCore, customers have a secure, governed environment to bring that high quality published data into their workflows without compromising how they manage their data.”

Gen Digital leads consumer and small business cyber safety, offering antivirus, antimalware, identity and privacy protection, virtual private networks, and cloud backup. Iskander Sanchez-Rola, Senior Director of AI & Innovation, Gen Digital shared “With the Web Search tool on Amazon Bedrock AgentCore, Norton Revamp helps professionals build their online reputation with current, grounded content ideas shaped by what’s actually happening in the world today. What we value most is that AWS uses its own search index and keep queries within our trusted AWS environment.”

To read more customer stories, visit the Amazon Bedrock Customers.

Now available
Web Search on Amazon Bedrock AgentCore is generally available today in the US East (N. Virginia) Region. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

You can get started with Web Search on Bedrock AgentCore at no additional cost. You pay only for the data transfer charges you use for the Gateway. New AWS customers also receive up to $200 in Free Tier credits. To learn more, visit the Amazon Bedrock AgentCore pricing page.

Try it in the Amazon Bedrock AgentCore console and send feedback to AWS re:Post for Amazon Bedrock AgentCore or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: AWS FinOps Agent in preview, Gemma 4 on Bedrock, Kiro Pro Max, and more (June 15, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-finops-agent-in-preview-gemma-4-on-bedrock-kiro-pro-max-and-more-june-15-2026/

This week, New York City is hosting AWS Summit, bringing together builders, customers, and AWS teams for a full day of announcements, demos, and technical sessions at the Javits Center. I wrote blog posts for some of the Summit launches, so I am excited to see them go live this week. I just won’t be watching from the Javits Center. I’ll be at a four-day music festival, following the launches on my phone while trying to figure out how to put up a tent. If you weren’t able to attend in person like me, the keynote livestream is available on June 17, with Dr. Swami Sivasubramanian, VP of Agentic AI, and Chet Kapoor, VP of Security Services and Observability, covering new capabilities across developer tools, AI infrastructure, and security.

Here’s what happened this week.

Headlines
How frontier teams are reinventing AI-native development — Swami published a detailed post this week drawing on data from experiments across hundreds of Amazon engineering teams. The findings are worth reading carefully if you are thinking about how to structure AI adoption on your own team.

A six-engineer team rebuilt the Amazon Bedrock inference engine in 76 days, a project originally scoped for 30 developers over 12 to 18 months. The median productivity gain across structured pilots with Amazon Stores teams was 4.5x in normalized deployment velocity, with some teams exceeding 10x. Perfect Order Experience went from a two-week feature cycle to shipping in an afternoon. WW Grocery cut design document creation from five days to a few hours.

The post distills these results into five practices for becoming a frontier team. First, invest in agent context: build steering files, coding standards, and structured repositories before writing production code. Second, expect an initial slowdown while workflows are restructured, and push through it. Third, maintain a steady backlog of well-scoped tasks so agents can run in parallel without constant supervision. Fourth, make intent explicit through structured specifications before code generation begins. Fifth, shift testing left so agents can self-correct before code reaches the pipeline.

The post closes with a note that commit velocity is only part of the picture, and that a follow-up will cover release management, operations, security operations, and EOL upgrades.

AWS FinOps Agent is now available in preview — AWS FinOps Agent is a new agent for FinOps practitioners and engineering teams that answers cost questions, surfaces optimization opportunities, investigates cost anomalies, and runs recurring FinOps workflows on a defined schedule. You can use it to query your AWS costs, generate cost reports for finance and engineering teams, and surface rightsizing, idle resource, and Savings Plans recommendations from AWS Cost Optimization Hub and AWS Compute Optimizer. The agent can open Jira tickets on your behalf based on those recommendations. When a cost anomaly is detected, FinOps Agent can automatically investigate the root cause and post findings to a Slack channel.

Last week’s launches
I’ll start with one I wrote this week, then cover the other launches that caught my attention:

  • Amazon EC2 M9g and M9gd instances are now generally available — Powered by AWS Graviton5 processors and built on the sixth-generation AWS Nitro System, M9g instances deliver up to 25% better compute performance compared to Graviton4-based instances, with up to 35% faster performance for web applications, up to 35% for machine learning inference, and up to 30% for databases. Graviton5 is the first processor in the AWS fleet to support PCIe Gen6 and DDR5-8800 memory, and includes a 5x larger L3 cache compared to the previous generation. M9g and M9gd instances offer up to 15% higher network bandwidth and 20% higher Amazon EBS bandwidth on average across sizes compared to M8g. This release also introduces the Nitro Isolation Engine, an enhancement to the Nitro System that uses formal verification to provide mathematically proven isolation between virtual machines — establishing Nitro as the first formally verified cloud hypervisor. M9gd instances add up to 11.4 TB of NVMe SSD local storage with 30% higher IOPS compared to M8gd. Both instance types support Instance Bandwidth Configuration (IBC) for adjusting bandwidth allocation between EBS and VPC networking by up to 25%.
  • Anthropic Claude Fable 5 on Amazon Bedrock — Claude Fable 5 launched on Amazon Bedrock on June 9, bringing extended asynchronous task execution, advanced vision capabilities across diagrams, charts, and PDFs, and proactive self-verification. Access requires opting into data sharing via the Data Retention API before invoking the model; Anthropic requires 30-day retention of inputs and outputs for Mythos-class models. Important note on availability: On June 12, Anthropic asked AWS to revoke access to Claude Fable 5 and Claude Mythos 5 for all users to support compliance with a US Government export control directive. All other models, including Opus 4.8, are unaffected. Read the Anthropic statement for details. AWS will share further updates as they become available.
  • Gemma 4 models are now available on Amazon Bedrock — The Gemma 4 family from Google DeepMind is now available on Amazon Bedrock across three variants: Gemma 4 31B (dense, 256K-token context window, suited for reasoning and coding workloads), Gemma 4 26B-A4B (mixture-of-experts architecture, targeting cost- and latency-sensitive workloads), and Gemma 4 E2B (smallest variant, designed for low-latency interactive use cases). All three support native function calling, structured output, reasoning, response streaming, multimodal input across text, image, video, and audio, and more than 35 languages.
  • Amazon OpenSearch Service launches MCP Apps for agentic observability — Amazon OpenSearch Service now supports MCP Apps, enabling observability workflows inside compatible agentic IDEs including Claude Desktop and VS Code. An AI agent in your local environment can investigate incidents using logs, traces, metrics, and alerts stored in OpenSearch domains, collections, and Amazon Managed Service for Prometheus. Each MCP App tool call returns a dual response: a text summary for the agent to reason over and an interactive visualization rendered in the same conversation thread. Available MCP App tools cover log, metrics, and trace investigation; service performance; topology; dynamic visualizations; agent health; cluster health; and instrumentation scoring.

Other AWS news
Here are some additional posts and updates you may find useful:

  • AWS CLI v1 enters maintenance mode — When CLI v1 enters maintenance mode, the botocore and s3transfer dependencies will be vendored directly into the CLI v1 codebase rather than installed as separate packages. This means upgrading CLI v1 will no longer update the standalone botocore or s3transfer packages, and installing those packages independently will have no effect on the versions used by CLI v1. Environments with both CLI v1 and boto3 installed will contain separate copies of these libraries. New CLI v1 releases will be limited to critical bug fixes and security issues. The recommended path is to migrate to AWS CLI v2.
  • AWS Workload Credentials Provider is now available — AWS has launched a new Workload Credentials Provider that enables workloads to obtain short-term AWS credentials without requiring long-term access keys. This supports credential management for applications running outside of AWS, giving teams a way to follow least-privilege access patterns for workloads in third-party or on-premises environments.
  • Kiro Pro Max is now available — Kiro has introduced a new Pro Max tier, adding higher usage limits, access to the latest frontier models, and additional agentic capabilities for development teams. Kiro Pro Max is designed for professional developers who need sustained, high-volume use across coding, specification generation, and agent-driven tasks.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building. You can also browse upcoming AWS-led in-person and virtual events, plus developer-focused sessions.

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Anthropic Claude Fable 5 on AWS: Mythos-class capabilities with built-in safeguards now available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/anthropic-claude-fable-5-on-aws-mythos-class-capabilities-with-built-in-safeguards-now-available/

Today, we’re announcing the availability of Claude Fable 5 on Amazon Bedrock and Claude Platform on AWS. Claude Fable 5 makes Mythos-level capabilities available to customers, with strong safeguards designed to make it safe for broader use. Fable 5 is state-of-the-art on nearly all tested benchmarks and delivers exceptional performance in software engineering, knowledge work tasks, and vision – built for ambitious, long running work.

With Claude Fable 5 on Bedrock, you can build within your existing AWS environment and scale inference workloads. You can also use Claude Fable 5 through the Claude Platform on AWS, giving you Anthropic’s native platform experience.

According to Anthropic, Claude Fable 5 represents a step-change in what you can accomplish with AI models. Here is what makes this model different:

  • Long-running, asynchronous execution — Claude Fable 5 handles complex tasks that previous models could not sustain, executing coding and knowledge work tasks for extended periods without intervention.
  • Advanced vision capabilities — Claude Fable 5 understands diagrams, charts, and tables nested in files and PDFs. This opens up research and document-heavy work in finance, legal, analytics, architecture, and gaming. In coding, the model implements designs with high fidelity and uses vision to critique its output against goals.
  • Proactive self-verification — The model self-updates skills based on learnings, develops its own harnesses and evaluations.

Claude Fable 5 includes safeguards that limit its performance in specific areas where misuse risk is elevated. Harmful prompts related to cybersecurity, biology, chemistry, and health fall back to receive a response from Opus 4.8 instead. Anthropic is able to expand access to nearly all of Claude Fable 5’s state-of-the-art capabilities by developing more powerful safeguards. The same model without these limits is Claude Mythos 5 and it will only be available to a small group of vetted customers.

Claude Fable 5 model in action
You can use Claude Fable 5 in both Amazon Bedrock and Claude Platform on AWS. This post will cover guidance on how to access and use on Amazon Bedrock. For guidance on the Claude Platform on AWS, visit the documentation to learn more.
To get started with Amazon Bedrock, you can access the model programmatically now using the Anthropic Messages API to call the bedrock-runtime or bedrock-mantle endpoints through Anthropic SDK. You can sole keep using the Invoke and Converse API on bedrock-runtime through the AWS Command Line Interface (AWS CLI) and AWS SDK.

In order to access Claude Fable 5 model, you must opt into data sharing by using the Data Retention API and setting provider_data_sharing before you can invoke the models. There is no console user interface for this setting at launch.

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: <your-bedrock-api-key>" \ 
  -H "Content-Type: application/json" \
  -d '{ "mode": "provider_data_share" }'

This mode allows Amazon Bedrock to retain and share your inference data with model providers per their requirements. Anthropic requires 30-day inputs and outputs retention, as well as human review. To learn more, visit the Amazon Bedrock abuse detection.

Let’s start with Anthropic SDK for Python using the Messages API on bedrock-mantle endpoint. Install Anthropic SDK.

pip install anthropic

Here is a sample Python code to call Claude Fable 5 model:

import anthropic

client = anthropic.Anthropic(
    base_url="https://bedrock-mantle.us-east-1.api.aws/anthropic",
    api_key= <your-bedrock-api-key>
)

message = client.messages.create( 
     model="anthropic.claude-fable-5", 
	 max_tokens=4096, 
	 messages=[ 
	     { "role": "user", 
		   "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions", 
		 }, 
	 ], 
)

print(message.content[0].text)

To learn more, check out Anthropic Messages API code examples and notebook examples for multiple use cases and a variety of programming languages.

You can also use Claude Fable 5 with the Invoke API and Converse API on bedrock-runtime endpoint. Here’s a example to call Converse API for a unified multi-model experience using the AWS SDK for Python (Boto3):

import boto3 
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1") 
response = bedrock_runtime.converse( 
    modelId="us.anthropic.claude-fable-5", 
    messages=[ 
        { 
            "role": "user", 
            "content": [ 
                { 
                    "text": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions." 
                } 
            ] 
        } 
    ], 
    inferenceConfig={ 
        "maxTokens": 4096 
    } 
) 
print(response["output"]["message"]["content"][0]["text"]) 

To learn more, visit code examples that show how to use Amazon Bedrock Runtime with AWS SDKs.

Things to know
Let me share some important technical details that I think you’ll find useful.

  • Model access — Claude Fable 5 access is gradually expanding for all AWS accounts. If your account doesn’t have access yet, it will be enabled soon depending on your Bedrock usage. If you want to get access to this model quickly, contact your usual AWS Support.
  • Pricing — When a harmful prompt is routed to Opus 4.8 instead of Fable 5, you pay only Opus prices. If a request is blocked mid-conversation, initial tokens are charged at Fable rates and subsequent tokens at Opus rates. To learn more, visit the Amazon Bedrock pricing page.
  • Data retention — For Fable 5, Mythos 5, and future models on Bedrock with similar or higher capability levels, Anthropic will require 30-day retention for all traffic on Mythos-class models. Retaining data for a limited period allows Anthropic to detect patterns of misuse that are not visible from a single exchange. Once you opt into data retention, your data will leave AWS’s data and security boundary.
  • Claude Mythos 5 on Bedrock (Limited Preview) — You can also use Anthropic’s most capable model for cybersecurity and life sciences, including vulnerability discovery, drug design, and biodefense screening. Access is currently limited due to the dual-use nature of these domains. To learn more, visit the model card documentation.

Now available
Anthropic’s Claude Fable 5 model is available today on Amazon Bedrock in the US East (N. Virginia) and Europe (Stockholm) Regions; check the full list of Regions for future updates. Claude Fable 5 is also available on the Claude Platform on AWS in North America, South America, Europe, and Asia Pacific.

Give Claude Fable 5 a try with the Amazon Bedrock APIs, in the Claude Platform on AWS, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Updated on June 9, 2026 — You can use the console on bedrock-runtime engine. The console support on bedrock-mantle is coming soon.

Automate medical record digitization with Amazon Bedrock Data Automation and AWS HealthLake

Post Syndicated from Gerardo Alarcon Rivas original https://aws.amazon.com/blogs/architecture/automate-medical-record-digitization-with-amazon-bedrock-data-automation-and-aws-healthlake/

Healthcare providers manage millions of paper medical records that remain disconnected from modern clinical systems. Clinicians make decisions without full patient histories, organizations spend millions on manual data entry, and critical information stays trapped in formats that modern applications can’t read. The technical challenge is clear: how do you transform unstructured, scanned documents into standardized, interoperable health data at scale, without building custom machine learning (ML) models or hand-coding document parsers for every form type.

In this post, you learn how to build an automated, serverless pipeline that converts scanned PDF medical records into FHIR R4-compliant data using Amazon Bedrock Data Automation and AWS HealthLake. We walk through the architecture, explain how each AWS service connects to the next, show you what the pipeline looks like when it runs, and get you deployed in under 20 minutes. For advanced configuration, troubleshooting, and customization options, see the GitHub repository.

The challenge with paper medical records

Healthcare organizations face a compounding problem. Paper records don’t only create storage challenges, they create care gaps. When a patient arrives at a new facility, clinicians often proceed with incomplete information because retrieving and interpreting historical records takes too long. Manual digitization is expensive, error-prone, and doesn’t scale.

The solution requires more than scanning documents. It requires extracting structured, clinically meaningful data and storing it in a format that integrates with existing systems. That’s where Fast Healthcare Interoperability Resources (FHIR) comes in. FHIR is the healthcare industry’s standard for exchanging electronic health information.

Solution overview

This solution uses an event-driven, serverless architecture to automate the full journey from PDF upload to queryable FHIR data. No custom machine learning models or manual template configuration are required.

AWS services used:

  • Amazon Bedrock Data Automation (BDA): Extracts over 50 structured clinical fields from scanned PDFs using advanced AI capabilities, including patient demographics, diagnoses with ICD-10 codes, medications, vital signs, and lab results.
  • AWS Lambda: Two serverless functions orchestrate the pipeline: a BDA Trigger function that fires when a PDF is uploaded, and a FHIR Processor function that converts extracted JSON into FHIR R4 format.
  • Amazon Simple Storage Service (Amazon S3): Input and output buckets with event notifications drive the pipeline automatically, with no polling or scheduled jobs required.
  • AWS HealthLake: A FHIR R4-compliant, HIPAA-eligible data store that validates, indexes, and exposes data through standard FHIR API endpoints.
  • AWS CloudFormation: Provisions the entire infrastructure as code in a single automated deployment (approximately 15–20 minutes).
  • Amazon CloudWatch and AWS CloudTrail: Provide end-to-end monitoring, logging, and audit trails across all pipeline components.
  • AWS Key Management Service (AWS KMS): Encrypts AWS HealthLake data at rest using customer managed keys.

Important: This solution is a demonstration sample designed for use with synthetic data only. It’s not production-ready for real Protected Health Information (PHI) without additional HIPAA security controls. See the Security considerations section before deploying in any environment with real patient data.

Architecture

End-to-end architecture showing the event-driven pipeline from PDF upload to FHIR-compliant data storage

Figure 1: End-to-end architecture showing the event-driven pipeline from PDF upload to FHIR-compliant data storage

The pipeline runs in three phases, each building on the last.

Phase 1: Infrastructure deployment

AWS CloudFormation provisions all required resources in a single stack: Amazon S3 input and output buckets, two Lambda functions, AWS Identity and Access Management (IAM) roles with least-privilege permissions, AWS KMS keys, CloudWatch log groups, and an AWS HealthLake FHIR R4 datastore. The entire environment, including all service-to-service permissions, is version-controlled and repeatable.

Phase 2: Event-driven data processing

The processing pipeline is fully event-driven. No scheduler or orchestration service is required. Each step triggers the next automatically:

  1. PDF Upload → S3 Input Bucket
  2. S3 Event → Triggers BDA Lambda function
  3. BDA Processing → Extracts over 50 clinical fields with confidence scores
  4. JSON Storage → S3 Output Bucket
  5. S3 Event → Triggers FHIR Processor Lambda function
  6. FHIR Conversion → Creates FHIR R4 Bundle (JSON + NDJSON)
  7. HealthLake Import → Automatic NDJSON ingestion and validation
  8. FHIR API Access → Query using HealthLake endpoints

Phase 3: Query and analytics

After the data is in AWS HealthLake, it’s immediately queryable using standard FHIR R4 API endpoints. Python scripts authenticate using AWS Signature Version 4 (SigV4) and support searches by patient, condition, medication, or lab result type.

How the services connect

Understanding the service interconnections is key to customizing or extending this solution.

Amazon S3 as the pipeline backbone

Amazon S3 plays a dual role: it’s both the entry point for raw PDFs and the handoff layer between processing stages. Amazon S3 event notifications remove the need for polling. When a PDF lands in the input bucket, the BDA Lambda fires immediately. When BDA writes its JSON output to the output bucket, the FHIR Processor Lambda fires automatically. This decoupled design means that each stage can scale independently.

Amazon Bedrock Data Automation as the intelligence layer

BDA serves as the intelligence layer. When Lambda triggers the extraction job, BDA retrieves the PDF from Amazon S3 and applies a custom medical blueprint, which is a schema defining the over 50 clinical fields to extract. The service understands document structure without requiring templates or training data. Each extracted field is returned with a confidence score (0.0–1.0), which the FHIR Processor Lambda uses to apply validation thresholds before conversion.

AWS Lambda as the transformation layer

The two Lambda functions are intentionally narrow in scope:

  • The BDA Trigger Lambda receives the Amazon S3 event, constructs the BDA API call, and submits the processing job.
  • The FHIR Processor Lambda reads BDA’s JSON output, maps each extracted field to the appropriate FHIR R4 resource type, assembles a FHIR Bundle, exports it as NDJSON, and triggers an AWS HealthLake import job.

This separation of concerns makes each function independently testable and replaceable.

AWS HealthLake as the FHIR data store

AWS HealthLake receives the NDJSON import, validates each resource against the FHIR R4 specification, creates relationships between resources (for example, linking Condition resources to their Patient), indexes data for efficient querying, and generates unique FHIR resource IDs. The result is a fully queryable FHIR data store accessible through authenticated API calls.

IAM roles as the security fabric

Each service communicates with the next using IAM roles with least-privilege permissions. There are no hardcoded credentials and no overly broad policies. Lambda functions assume roles that grant only the specific actions they need (for example, bedrock-data-automation:InvokeDataAutomationAsync and s3:GetObject for the BDA Trigger Lambda).


Walkthrough

This walkthrough takes you from prerequisites through deployment and verification.

Prerequisites

Before deploying, confirm you have the following:

Required software:

  • Python 3.10 or later.
  • Poetry (Python dependency management).
  • AWS Command Line Interface (AWS CLI) configured with appropriate credentials.

Verify your Poetry installation:

poetry --version

If you need to install Poetry:

curl -sSL https://install.python-poetry.org | python3 -

Required AWS permissions:

You need IAM permissions for the following services:

  • Amazon Bedrock Data Automation.
  • AWS CloudFormation (create, update, and delete stacks).
  • Amazon S3 (create buckets, upload and download objects).
  • AWS Lambda (create and update functions).
  • AWS Identity and Access Management (IAM) (create roles and policies).
  • AWS HealthLake (create data stores).

Supported AWS Regions:

This solution currently supports us-east-1 (US East N. Virginia) and us-west-2 (US West Oregon) only. These are the Regions where Amazon Bedrock Data Automation is available.


Deploy the pipeline

Deployment takes approximately 15–20 minutes. Run the following four commands to go from zero to a fully deployed pipeline:

# 1. Clone the repository and install dependencies
git clone <repository-url>
cd Medical-Record-Digitization-and-FHIR-Integration-Pipeline
poetry install

# 2. Configure your environment
poetry run python src/utils/setup_env.py

# 3. Deploy the CloudFormation stack (approximately 15 minutes)
poetry run python src/automation/deploy.py

# 4. Verify deployment
aws cloudformation describe-stacks \
  --stack-name bda-medical-records-stack \
  --query 'Stacks[0].StackStatus'
# Expected output: "CREATE_COMPLETE"

The deployment creates the following resources:

  • Amazon Bedrock Data Automation blueprint and project (custom medical records schema with over 50 fields).
  • Amazon S3 input and output buckets with automatic event notifications.
  • Two AWS Lambda functions (BDA Trigger and FHIR Processor).
  • AWS HealthLake FHIR R4 data store.
  • AWS Identity and Access Management (IAM) roles and policies with least-privilege permissions.
  • Amazon CloudWatch log groups for all Lambda executions.

For manual environment configuration, advanced deployment options, and troubleshooting, see the GitHub repository.


See it in action

After it’s deployed, upload a sample medical record to trigger the full pipeline. You can use the sample provided in the GitHub repository.

# Get your input bucket name from the CloudFormation stack output
INPUT_BUCKET=$(aws cloudformation describe-stacks \
  --stack-name bda-medical-records-stack \
  --query 'Stacks[0].Outputs[?OutputKey==`InputBucketName`].OutputValue' \
  --output text)

# Upload a sample PDF (use the synthetic records included in the repository)
aws s3 cp samples/medical-record-sample.pdf s3://$INPUT_BUCKET/

# Track BDA processing jobs
poetry run python src/utils/track_bda_jobs.py

Within 2–3 minutes, Amazon Bedrock Data Automation processes the PDF and the FHIR Processor Lambda imports the results into HealthLake. View the extracted data:

poetry run python src/utils/view_results.py

Example output:

Found 8 result files in output bucket
Processing: medical-record-sample_results.json

Patient Information:
---------------------
Name: Wilkins, Samantha
Patient ID: A1B2C3D4
Date of Birth: 10/28/1953

Conditions (5 found):
- Hypothyroidism (ICD-10: E03.9) - Confidence: 0.98
- Vitamin D Deficiency (ICD-10: E55.9) - Confidence: 0.95
- Hypertension (ICD-10: I10) - Confidence: 0.97
- Osteoarthritis (ICD-10: M19.90) - Confidence: 0.92
- Gastroesophageal Reflux Disease (ICD-10: K21.9) - Confidence: 0.96

Medications (4 found):
- Levothyroxine 100 mcg daily
- Vitamin D3 2000 IU daily
- Lisinopril 10 mg daily
- Omeprazole 20 mg daily
Lab Results (16 tests):
TSH: 2.3 mIU/L (Normal range: 0.4-4.0) ✓
Vitamin D: 28 ng/mL (Normal range: 30-100) ⚠
Blood Pressure: 128/82 mmHg (Stage 1 Hypertension) ⚠

[✅] FHIR conversion complete
[✅] Imported to HealthLake datastore: ds-abc123xyz456

Query FHIR data from AWS HealthLake

After ingestion, query your data using the interactive FHIR query interface:

poetry run python src/utils/query_medical_data.py

Supported FHIR query patterns:

# Search by patient name
Patient?name=Wilkins

# Get conditions for a specific patient
Condition?patient=Patient/47ef817a-9826-4498-b693-2af5eb2b5250

# Get lab results only
Observation?category=laboratory

# Get vital signs only
Observation?category=vital-signs

# Get all medications
MedicationRequest

Python example, authenticated FHIR API call:

import boto3, requests, os
from botocore.auth import SigV4Auth
from botocore.awsrequest import AWSRequest

session = boto3.Session()
credentials = session.get_credentials()
region = os.environ.get('AWS_REGION', 'us-west-2')
datastore_id = os.environ.get('DATASTORE_ID')

url = f'https://healthlake.{region}.amazonaws.com/datastore/{datastore_id}/r4/Patient?name=Wilkins'
request = AWSRequest(method='GET', url=url, headers={'Accept': 'application/fhir+json'})
SigV4Auth(credentials, 'healthlake', region).add_auth(request)

response = requests.get(url, headers=dict(request.headers))
print(response.json())

Security considerations

This is a demonstration sample for synthetic data only. Do not use with real Protected Health Information (PHI) without implementing the controls listed in the following sections.

Security controls included in this sample:

  • IAM roles with least-privilege permissions.
  • Amazon S3 bucket access controls (private by default).
  • AWS KMS encryption for AWS HealthLake data at rest.
  • AWS service-to-service authorization using IAM roles.
  • Amazon CloudWatch logging for audit trails.

Additional controls required for production PHI workloads:

AWS HealthLake is a HIPAA Eligible Service. Customers must review the AWS Shared Responsibility Model to understand their security and compliance obligations. Before processing real patient data, implement the following:

  1. AWS Business Associate Addendum (BAA): Required under HIPAA before processing PHI on AWS.
  2. Amazon Virtual Private Cloud (Amazon VPC) isolation: Lambda functions and AWS HealthLake in private subnets with AWS PrivateLink.
  3. Comprehensive logging: AWS CloudTrail, AWS Config, Amazon S3 access logs, and Amazon VPC flow logs.
  4. Encryption in transit: TLS 1.2 or later. Use Amazon VPC endpoints to avoid public internet exposure.
  5. Access controls: Multi-factor authentication (MFA), role-based access control (RBAC), temporary credentials, and regular access reviews.
  6. Compliance monitoring: AWS Security Hub with HIPAA compliance checks.
  7. Data lifecycle management: Retention policies, secure deletion, and data loss prevention (DLP) controls.

For full guidance, see the AWS HIPAA Compliance page.

Pricing

The following estimates apply to testing with approximately 100 medical records per month in the US West (Oregon) Region:

Service Usage Estimated monthly cost
Amazon Bedrock Data Automation 100 pages (approximately $0.20–$0.30/page) $20–$30
AWS HealthLake 5 GB storage + 100 queries $15–$20
AWS Lambda 200 invocations (512 MB, approximately 30s avg) $5–$10
Amazon S3 1 GB storage + 200 requests $1–$2
AWS KMS 1 customer managed key $1
Total approximately $50–$100/month

For production workloads processing 10,000 records per month, expect costs in the range of $2,000–$3,000/month. The primary cost drivers are BDA (charged per page), HealthLake (charged per search request), and VPC endpoints (hourly PrivateLink charges in production deployments).

Cost optimization tips:

  • Delete the CloudFormation stack when not actively testing: aws cloudformation delete-stack --stack-name bda-medical-records-stack.
  • Set up AWS Budgets alerts to catch unexpected costs early.
  • Monitor Lambda duration in CloudWatch to optimize function execution time.

Clean up

To avoid ongoing charges, delete the CloudFormation stack when you’re done:

aws cloudformation delete-stack --stack-name bda-medical-records-stack
aws cloudformation wait stack-delete-complete --stack-name bda-medical-records-stack

For cleanup of manually created Amazon Bedrock Data Automation projects and S3 bucket contents, see the GitHub repository.

What’s next

After you deploy, you can extend this foundation to:

  • Integrate with existing electronic health records (EHR) systems through FHIR APIs.
  • Build analytics dashboards using Amazon Quick Sight.
  • Add natural language search with Amazon Kendra.
  • Add Amazon Simple Queue Service (Amazon SQS) as a buffer between Amazon S3 events and the BDA Trigger Lambda to handle burst uploads and manage BDA concurrency limits at scale.
  • Orchestrate with AWS Step Functions for error handling, retry logic, and routing low-confidence extractions to human review.
  • Implement real-time, high-volume processing with Amazon Kinesis Data Streams for continuous ingestion from multiple sources.

Conclusion

In this post, you saw how Amazon Bedrock Data Automation, AWS Lambda, Amazon S3, and AWS HealthLake work together to automate the transformation of scanned medical records into FHIR R4-compliant data. The event-driven architecture removes manual data entry, scales without custom machine learning models, and makes historical records accessible to modern care delivery systems.

Key takeaways:

  • Amazon Bedrock Data Automation extracts over 50 structured clinical fields from PDFs without template configuration.
  • AWS Lambda orchestrates the pipeline with two focused, event-driven functions.
  • Amazon S3 event notifications decouple each stage, so each can scale independently.
  • AWS HealthLake validates, indexes, and exposes FHIR R4 data through standard APIs.
  • Security controls are the customer’s responsibility under the AWS Shared Responsibility Model.

To explore the full source code, advanced configuration options, and customization guidance, visit the GitHub repository.


Additional resources

For more information, see the following additional resources:

This solution is intended for educational purposes using synthetic data. Review the security considerations and consult your compliance team before deploying in any environment with real patient data.


About the authors

AWS Weekly Roundup: BYOM for Amazon RDS for SQL Server, AWS IoT Device SDK for Swift, and more (June 8, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-byom-for-amazon-rds-for-sql-server-aws-iot-device-sdk-for-swift-and-more-june-8-2026/

This week, the AWS IoT Device SDK for Swift reached general availability. As a member of the Swift Server Workgroup (SSWG), this one caught my attention. The SDK brings production-ready MQTT 5 connectivity, Device Shadow, Jobs, and fleet provisioning to Swift developers on macOS, iOS, tvOS, and Linux.

Swift on IoT and Edge devices, an AI generated illustration

I’m curious to see what you will build with it. Swift on the server has matured over the past few years, and now it reaches IoT devices too. This connects to a broader trend of running Swift at the edge. WendyOS, for example, is an open-source operating system for physical AI that offers first-class Swift support for deploying apps to NVIDIA Jetson and Raspberry Pi hardware. Between server-side Swift, IoT, and edge computing, the language is showing up in places that would have surprised most people a few years ago.

Now, let’s get into this week’s AWS news.

Headlines
Amazon RDS for SQL Server supports Bring Your Own Media — Customers who migrate SQL Server applications from on-premises environments can now reuse their existing Microsoft SQL Server licenses, including Software Assurance, through Microsoft’s License Mobility program on Amazon RDS. BYOM is integrated with AWS License Manager for tracking license usage and compliance. Read more.

Amazon Cognito now supports multi-Region replication — You can now synchronize user and machine identity data, including credentials, user pool configurations, and federation setups, to a secondary user pool in a standby Region in near real-time. In the event of a disruption in the primary Region, signed-in users continue accessing their applications without re-authenticating, and registered users can sign in with their existing credentials. Multi-Region replication is available as an add-on for user pools in Essentials or Plus feature tiers across 16 Regions. Read more.

GPT-5.5, GPT-5.4, and Codex from OpenAI are now generally available on Amazon Bedrock — You can now use GPT-5.5 and GPT-5.4 in production workloads on Amazon Bedrock and build with Codex for AI-powered software development, with the same security, governance, and operational controls you already use across AWS. GPT-5.5 is the most capable model from OpenAI, excelling at agentic coding, data analysis, and multi-step autonomous tasks. Codex is available through the Codex App, the Codex CLI, and IDE integrations with Visual Studio Code, JetBrains, and Xcode. Pricing matches OpenAI first-party rates, and usage counts toward existing AWS commitments. Read more.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Upcoming AWS events
Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

Try the new console experience in Amazon Bedrock, optimized for Anthropic- and OpenAI-compatible APIs

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/try-the-new-console-experience-in-amazon-bedrock-optimized-for-anthropic-and-openai-compatible-apis/

Today, we’re announcing a new console experience in Amazon Bedrock for you to experiment, iterate, and scale with the latest AI models on Amazon Bedrock’s next-generation inference engine built for high performance, reliability, and security. This console has a refreshed workflow optimized for bedrock-mantle endpoint, which supports the latest GPT, Claude, and open-weight models with the OpenAI Responses API, OpenAI Chat Completions API, and the Anthropic Messages API.

The new console experience makes it simple to find the right model and move quickly from evaluation to production.

  • New model card – You can browse the full model catalog, compare them side by side on capabilities, modality support, context window, and applicable service quotas in a single view, removing the need to stitch together documentation, and limit calculators.
  • Project-based work – You can make a project to run evaluations and review usage insights in one streamlined workflow that mirrors the lifecycle of building a generative AI application.
  • Live documentation – You can use project-aware live documentation: code samples, SDK snippets, and API references are automatically prefilled with your project variables. You can copy a snippet straight from the console into your application and run it without modification.

How to get started
You can try a new experience by choosing Try the Bedrock Mantle Console from within the Amazon Bedrock console, or by using the new console link directly.

You can find a project-based dashboard to show inference requests and error by range of recent dates, recently used models, and the project list. You can create a project, assign models, configure API keys, and start making inference requests in minutes.

A new model catalog shows the latest GPT, Claude, and open-weight models that are supported on the bedrock-mantle engine. You can see the details of features, tokens, pricing, input/output, pricing information, and Regional availability. You can also compare up to 3 models in a single view.

When you choose the project dashboard, you can see the models used in the project, the distribution of your token usage such as total token usage, token usage per minute, inference requests per minute, and tokens per inference request. This can inform your model selection, prompt optimization, and workload consistency decisions.

You can select up to 3 models to start evaluating to compare responses side by side with the same prompt.

To build your application in the project, choose Getting started. You can migrate existing code, build a new app with the Anthropic or OpenAI SDK, or connect an AI coding assistant to Bedrock.

Choose the API & SDK, your SDK (either Anthropic or OpenAI), your preferred programming language, and your authentication method. It shows your environment code to run these in your terminal for a quick test, or save to a .env file for your application. You can also send your first request with sample code snippets to verify your setup.

When you choose Clients, you can select the AI coding agent source such as Claude Code, Cline, Codex, Cursor, or OpenCode that you want to connect to the bedrock-mantle engine. It provides instructions on how to install the AI agent, use your AWS IAM credentials or use a Bedrock API key, set environment variables, and route requests from each AI agent through Bedrock.

To learn about Anthropic- and OpenAI-compatible APIs, choose Live API docs. You can choose Anthropic API Protocol for access to Claude model features like the Messages API or OpenAI API Protocol for access to features like Responses API.

For example, when you choose OpenAI Response API, it retrieves a model response with the given model ID. These API references are automatically prefilled with the project’s selected model ID, Region, bedrock-mantle endpoint URL, and API key reference, and they update in place as you change models or settings.

You can also choose the existing Bedrock console to manage fully-managed features such as Agents, Knowledge Bases, Guardrails, fine-tuning, or the InvokeModel and Converse APIs to run on the bedrock-runtime endpoint.

Now available
The new console experience is available in all AWS Regions where the bedrock-mantle endpoint is offered: US East (N. Virginia, Ohio), US West (Oregon), Asia Pacific (Jakarta, Mumbai, Sydney, Tokyo), Europe (Frankfurt, Ireland, London, Milan, Stockholm), and South America (São Paulo). Check the full list of Regions for future updates.

Give the new console experience a try in the new Amazon Bedrock console and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Automating contract intelligence with Doczy.ai™ on AWS

Post Syndicated from Sanket Nasre original https://aws.amazon.com/blogs/architecture/automating-contract-intelligence-with-doczy-ai-on-aws/

Extracting actionable insights from thousands of contracts and legal documents remains a challenge. For organizations, critical business information is locked in unstructured documents such as contracts, legal agreements, provider arrangements, and vendor invoices. Extracting and operationalizing this information has traditionally been a manual, error-prone, and resource-intensive process. This leads to missed savings opportunities, costly delays, and significant inefficiencies across the enterprise.

AArete, a global management and technology consulting firm specializing in healthcare, recognized this challenge and developed Doczy.ai™, an intelligent contract interpretation solution powered by generative AI on Amazon Web Services (AWS).

In this post, we show you how Doczy.ai™ uses generative AI on AWS to automate contract intelligence at scale, transforming unstructured documents into structured, actionable insights, so organizations can automate critical business processes and unlock the full value of their data.

The challenge: Data trapped in documents

For healthcare organizations, managing and interpreting contracts and documents represents a major operational bottleneck. Manual review processes require deploying teams to extract data from thousands of documents. This is an approach that is neither scalable nor sustainable, highly prone to error, and costly. Organizations relying on institutional knowledge face additional risks: critical information resides with a few key individuals, creating knowledge silos and succession planning challenges. Existing Contract Lifecycle Management (CLM) systems often prove inadequate for capturing the nuanced and complex terms unique to each agreement. These legacy systems can only configure predefined fields, missing the rich detail and contextual information that distinguishes contracts. The downstream impact is substantial: in healthcare, reimbursement terms must be manually translated into claims systems—a slow, error-prone process. Similarly, verifying vendor invoices against contract terms often requires manual effort, leading to payment processing delays and missed contractual savings opportunities. These inefficiencies ultimately leave significant value on the table.

This is where Doczy.ai™ provides significant value.

Doczy.ai™: An intelligent contract interpretation solution

Doczy.ai™ directly addresses these challenges using advanced AI and scalability on AWS. Developed by AArete, Doczy.ai™ pushes the boundaries of document intelligence. The solution automatically interprets complex documents and converts them into a structured, queryable information repository that allows organizations to unlock the full value of their data and drive smarter decisions.The evolution of Doczy.ai™ reflects rapid AI advancement. Prior to 2020, document processing required manual effort, with individuals processing approximately 100 documents per week. Between 2020–2023, the firm implemented rules-based contract processing, achieving approximately 55% accuracy. The breakthrough came in 2024 with an AI-based processing built on AWS achieved 99% accuracy—a dramatic improvement over the 55% accuracy of traditional rules-based systems.

Doczy.ai™ architecture

Doczy.ai™ is built on a comprehensive AWS architecture designed to handle the entire document processing lifecycle: from the moment a file enters the system to the moment it generates actionable business intelligence.

Doczy.ai is built on a comprehensive AWS architecture designed to handle the entire document processing lifecycle: from the moment a file enters the system to the moment it generates actionable business intelligence.

Architecture of Doczy.ai™

External users access the platform through a secure Next.js frontend, with Amazon Cognito managing authentication and authorization behind the scenes. After authentication, users upload documents directly to Amazon Simple Storage Service (Amazon S3), where durable, scalable object storage ensures nothing is lost and everything is accessible at scale. From there, the real intelligence begins.

An AWS Lambda function triggers Amazon Textract to extract text and metadata from documents in various formats. What sets Doczy.ai™ apart at this stage is its patented “smart chunking” algorithm, a proprietary approach that goes far beyond pulling words off a page. Rather than treating a document as a flat sequence of text, smart chunking preserves hierarchical structure and one-to-many relationships within documents. It uses a combination of semantic and keyword search to decompose text into meaningful, context-aware chunks, applying dynamic parameters to maintain logical relationships throughout. Sequential identifiers and metadata-driven grouping organize these chunks into field groups, detecting overlaps and removing duplications while keeping the document’s natural flow intact.

After chunking, the document enters the dual clustering engine of Doczy.ai™. This two-lens methodology analyzes every contract simultaneously from both a semantic and a structural perspective. On the semantic side, extracted text is converted into embeddings, numerical representations of meaning, and similar ideas are grouped together even when they’re expressed in different words. On the structural side, pattern-recognition algorithms identify clause types, formatting conventions, table layouts, and hierarchical organization, understanding. For example, that a three-nested-level exhibit carries fundamentally different implications than a straightforward attached schedule.These two analyses don’t operate in isolation. Projection algorithms compare the semantic and structural clusters side by side, synthesizing them into a unified, enriched document model that captures both meaning and context. It’s this convergence that drives the 99% accuracy rate of Doczy.ai™. The system doesn’t just read the words, it understands the contract. Advanced large language models (LLMs) then generate structured output grounded in this dual-clustered intelligence.Before output is finalized, the system determines each document’s file class and generates prompts tailored to the extracted text, cluster classification, and domain context. Through few-shot and multi-shot prompting, the platform continuously edits the prompt on domain-specific examples and based on real outputs, creating a feedback loop that compounds accuracy improvements over time.

The resulting structured data flows into Snowflake, forming a centralized repository that powers intelligent dashboards with actionable insights and visualizations. Throughout the entire pipeline, Amazon CloudWatch monitors performance in real time and proactively surfaces issues before they escalate, while AWS Secrets Manager safeguards sensitive information, ensuring that security is not an afterthought, but a foundational layer woven into every stage of the system.

The transformative impact of Doczy.ai™

The results of this AI-powered approach are transformative and measurable. By automating contract interpretation and document processing, Doczy.ai™ has demonstrated significant impact at scale for multiple organizations across healthcare and financial services. The scale of operations over the last 22 months demonstrates the maturity and production readiness of Doczy.ai™. This solution has processed 2.5 million contract documents (50 million pages) with 137 million API calls to Amazon Bedrock and 442 billion tokens—a level of automation and accuracy previously unattainable through manual or traditional document processing approaches. Over this same period, Doczy.ai™ has helped clients achieve approximately 330 million dollars in cumulative direct and indirect savings.The 99% accuracy rate represents significant improvement over the approximately 55% accuracy of rules-based systems and far exceeds manual processing, which is typically affected by fatigue and human error. The 97% reduction in manual processing time translates directly to cost savings and enables organizations to reallocate human resources to higher-value activities that require judgment and strategic thinking.

A use case in action: Business process automation for health plans

For health plans, Doczy.ai™ provides a powerful solution to automate and improve contract management across the entire lifecycle. It ingests existing contracts in both paper and digital formats, integrates with contract management systems such as Coupa and Icertis, and processes new contracts and amendments as they’re executed. It then creates a centralized metadata repository that feeds directly into downstream systems, enabling end-to-end business process automation.This automation unlocks critical capabilities: Organizations can continuously analyze and improve contract terms, identifying opportunities to improve financial performance and operational efficiency. The architecture feeds accurate, up-to-date contract data directly into claims systems, automating the configuration process that previously required manual translation of reimbursement terms and removing manual data entry, configuration errors, and delays. Additionally, the platform helps maintain claim payment accuracy by assessing payments against contract terms, identifying discrepancies, and flagging potential overpayments or underpayments before they occur.By automating manual processes, health plans can adapt quickly to new contract terms and regulatory requirements. The intelligent dashboards and actionable insights provided by Doczy.ai™ enable decision-makers to understand contract performance, identify trends, and take proactive action to optimize financial outcomes.

Getting started with Doczy.ai™

Organizations interested in using Doczy.ai™ to transform document processing and contract management can engage with AArete to discuss their specific use cases and requirements. AArete offers the platform as a Software as a Service (SaaS) solution, enabling rapid deployment without significant infrastructure investment. AArete’s team of experts will configure this solution for your specific document types, domain terminology, and business processes, supporting maximum value from day one.

Conclusion

The challenge of unlocking data from unstructured documents is a major hurdle for many businesses, particularly in healthcare and financial services where contracts and agreements govern critical operational and financial relationships. By embracing intelligent document intelligence on AWS, organizations can solve this long-standing operational challenge and unlock a new frontier of strategic advantage, turning their data into their most valuable asset.

Built on a sophisticated architecture that orchestrates Amazon Cognito, Amazon S3, AWS Lambda, Amazon Textract, Amazon Elastic Container Service (Amazon ECS), Amazon Bedrock, Amazon CloudWatch, and AWS Secrets Manager, Doczy.ai™ demonstrates how modern cloud services can solve complex document-heavy business problems. Its advanced hybrid smart chunking, dual clustering, and prompt optimization techniques form the core of a patented contract intelligence engine.

Doczy.ai™ delivers tangible impact, processing up to 250,000 contract documents per week with 99% accuracy, reducing manual processing time by 97%, and helping clients unlock roughly 330 million dollars in cumulative savings over 22 months. By embracing this intelligent document processing, organizations can turn contracts into a strategic data asset, improving efficiency, accuracy, and profitability while freeing teams to focus on higher-value work.

To learn more about how AArete and Doczy.ai™ can help your organization transform document processing and unlock the value of your unstructured data, visit the AArete website.


About the authors

Get started with OpenAI GPT-5.5, GPT-5.4 models, and Codex on Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/get-started-with-openai-gpt-5-5-gpt-5-4-models-and-codex-on-amazon-bedrock/

As we previewed in What’s Next with AWS 2026, we’re announcing the general availability of OpenAI GPT-5.5, GPT-5.4 models, and Codex on Amazon Bedrock, giving you access to frontier models and a coding agent for software development.

According to OpenAI, GPT-5.5 and GPT-5.4 models are excellent for coding, reasoning, agentic workflows, and complex professional work. You can use GPT-5.5 for the hardest customer workloads and GPT-5.4 for the best price-performance. You can call them through Responses API on Amazon Bedrock’s next-generation inference engine built for high performance, reliability, and security.

Codex is the OpenAI coding agent for AI-powered software development. According to OpenAI, more than 4 million developers use Codex every week to write, refactor, debug, test, and validate code across large codebases. With GPT-5.5 powering inference, Codex introduces a new class of intelligence optimized for complex, long-horizon developer workflows. You can use the Codex App, the Codex CLI, and IDE integrations with Visual Studio Code, JetBrains, and Xcode, with all model inference routed through the Responses API on Amazon Bedrock.

For customers with data residency requirements, all processing stays within the Bedrock Region you select. You pay per token with no seat licenses and no per-developer commitments.

GPT-5.5 and GPT-5.4 models on Bedrock in action
You can access the model programmatically using the OpenAI Responses API to call the bedrock-mantle endpoints through the OpenAI SDK, command-line tools such as curl.

Let’s start with OpenAI SDK for Python. Install OpenAI SDK.

pip install -U openai

Set the environment variables for authentication.

export OPENAI_BASE_URL="https://bedrock-mantle.us-east-2.api.aws/openai/v1"
export OPENAI_API_KEY="<BEDROCK_API_KEY>"
export BEDROCK_OPENAI_MODEL_ID="openai.gpt-5.5"

Here is a sample Python code to call GPT-5.5 model on Bedrock:

import os
from openai import OpenAI
 
client = OpenAI(
    base_url=os.environ["OPENAI_BASE_URL"],
    api_key=os.environ["OPENAI_API_KEY"],
)
 
response = client.responses.create(
    model=os.environ["BEDROCK_OPENAI_MODEL_ID"],
    input=[
        {
            "role": "developer",
            "content": "You are a software engineer with excellent AWS cloud knowledge. Be concise and practical.",
        },
        {
            "role": "user",
            "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions.",
        },
    ],
    reasoning={"effort": "medium"},
    text={"verbosity": "low"},
)
 
print(response.output_text)

You can call directly the model endpoint using curl.

curl "$OPENAI_BASE_URL/responses" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -d '{
    "model": "openai.gpt-5.5",
    "input": [
      {
        "role": "developer",
        "content": "You are a software engineer with excellent AWS cloud knowledge."
      },
      {
        "role": "user",
        "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."
      }
    ],
    "reasoning": {"effort": "medium"},
    "text": {"verbosity": "low"}
  }'

You can use the Responses API when you want to use model-managed multi-turn state, need hosted tools, function tools, or richer tool orchestration, and run background or long-running work. To learn more, visit the OpenAI Cookbook Responses examples.

Using OpenAI Codex with GPT-5.5 on Amazon Bedrock
You can download Codex CLI, Codex App or Codex VS Code extension and get started with the Bedrock for model inference. Codex supports two Bedrock authentication pathways: Amazon Bedrock API key or AWS SDK credential chain. If you set AWS_BEARER_TOKEN_BEDROCK, Codex uses it first; otherwise Codex falls back to AWS SDK credential chain.

Set AWS_BEARER_TOKEN_BEDROCK in the environment that Codex will read:

export AWS_BEARER_TOKEN_BEDROCK=<your-bedrock-api-key>

Then, configure your preferred Region and set the model ID to openai.gpt-5.5 in ~/.codex/config.toml, which is required for Bedrock API-key authentication. You can also choose openai.gpt-5.4, openai.gpt-oss-120b, or openai.gpt-oss-20b. For the desktop app or VS Code extension, put any environment variables the app needs in ~/.codex/.env.

model = "openai.gpt-5.5"
model_provider = "amazon-bedrock"
[model_providers.amazon-bedrock.aws]
region = "us-east-2"

Restart the desktop app or VS Code extension after changing ~/.codex/config.toml or ~/.codex/.env. In Codex CLI, you should see a /status tab that looks like this:

In Codex App, you can use GPT-5.5 model through Amazon Bedrock inference.

Things to know
Let me share some important technical details that I think you’ll find useful.

  • Model latency: OpenAI model information positions GPT-5.5 as fast and GPT-5.4 as medium speed, but customer-perceived latency depends on reasoning effort, output length, tool calls, background mode, Region, quotas, throttling, prompt size, and cache hits. Start GPT-5.5 at medium effort. Start GPT-5.4 with effort set explicitly rather than relying on its none default.
  • Scaling and capacity: Bedrock’s new inference engine is designed to rapidly provision and serve capacity across many different models. When accepting requests, we prioritize keeping steady state workloads running, and ramp usage and capacity rapidly in response to changes in demand. During periods of high demand, requests are queued, rather than rejected.

Now available
OpenAI GPT models and Codex on Amazon Bedrock are available today: GPT-5.5 model in the US East (Ohio) Region, GPT-5.4 model in the US East (Ohio) and US West (Oregon) Regions. Check the full list of Regions for future updates. To learn more, visit the OpenAI on Amazon Bedrock page and the Amazon Bedrock pricing page.

Give GPT-5.5, GPT-5.4 models, and Codex on Amazon Bedrock a try today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Claude Opus 4.8 on AWS, Aurora MySQL with Kiro Powers, and more (June 1, 2026)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-8-on-aws-aurora-mysql-with-kiro-powers-and-more-june-1-2026/

In my last Week in Review post, I shared what I’d been hearing from customers in the AI-Driven Development Lifecycle (AI-DLC) workshops I’ve been delivering. Last week I was back at it, this time in Denver for a two-day AI-DLC workshop, where I helped facilitate 17 teams to deliver nearly 20 separate use cases in just two days. The pace of acceleration that AI-DLC unlocks—especially when paired with tools like Claude Code on Amazon Bedrock—is fundamentally changing how businesses operate. Traditional roles within software development teams are collapsing into smaller, AI-augmented squads, and the paradigm shift is beginning to take place right in front of us. To learn more about how to utilize various AI tools, visit the GitHub repository of AI-DLC workflow.

This shift is also reshaping how AWS account teams (solutions architects, customer solutions managers, and technical account managers) collaborate with customers. It’s becoming less about handing off advisory design documents and more about building alongside them in real time. It’s a genuinely exciting moment to be in the middle of the change, and this week’s headline launch — Anthropic’s most capable model yet, now on AWS — is going to push that pace even further.

Now, let’s get into this week’s AWS news…

Headlines
Claude Opus 4.8 on AWS — Anthropic’s most capable generally available model is now accessible through both Amazon Bedrock and the Claude Platform on AWS. Opus 4.8 is built for agentic coding, knowledge work, and extended autonomous task execution — it sustains longer autonomous sessions with deeper reasoning, recovers from errors, and synthesizes information across lengthy documents. For coding workloads, it reads codebases like an engineer, plans before it edits, and holds context across long sessions. On Amazon Bedrock, you get AWS-managed features like Guardrails, Knowledge Bases, and data residency; on the Claude Platform on AWS, you get Anthropic’s native APIs unified with AWS billing. To learn more, visit the deep-dive blog post.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Introducing the next generation of AWS Resilience Hub — A reimagined Resilience Hub gives SREs and developers a unified framework to define resilience standards, evaluate applications against them, and demonstrate compliance across an entire portfolio. It introduces modular resilience policies (covering service-level objectives (SLOs), multi-AZ/Region DR, and data recovery), business-oriented application modeling, generative AI-powered assessments aligned with the Well-Architected and Resilience Analysis Frameworks, and automatic dependency discovery via DNS query log analysis. Integration with AWS Organizations enables organization-wide resilience management from a single delegated administrator account.
  • Introducing the next generation of Amazon OpenSearch Serverless for building agentic AI applications — Amazon OpenSearch Serverless is now a fully managed search and vector engine purpose-built for agentic AI applications. It scales from zero to thousands of requests per second—roughly 20x faster than the prior generation—delivers up to 60% cost savings versus peak-provisioned clusters, and adds GPU acceleration plus new SEARCH and VECTORSEARCH collection types. Native integrations with Vercel, Kiro, Claude Code, and Cursor through OpenSearch Agent Skills make it straightforward to plug into your agent stack.
  • New assessment capabilities in AWS Transform — AWS Transform expands with new tools to help you build migration business cases and evaluate TCO before moving workloads to AWS. You can ingest data from RVTools exports, CMDB data, the AWS Transform discovery tool, and third-party discovery tools, then run what-if scenarios across region, utilization, and service mapping for EC2, FSx, S3, SQL Server on EC2, and virtual desktops. The release also adds Agentic Readiness Analysis (ARA) and Modernization Analysis (MODA), which scan code repositories in 5 to 30 minutes per repo to surface severity-tagged findings with file-level evidence and AWS-mapped remediation guidance.
  • Amazon Aurora MySQL with Kiro Powers — Aurora MySQL now integrates with Kiro Powers, drawing from a curated repository of pre-packaged MCP servers, steering files, and hooks validated by Kiro partners. Developers can execute both data plane tasks (queries, schema management) and control plane tasks (cluster management) in natural language, with dynamic guidance for Aurora MySQL Serverless scaling, RDS-to-Aurora migration, and replication setup. The companion Database Blog post explains how the agent produces the API calls, SQL, and configuration for you to review and run — available via one-click install from the Kiro IDE or webpage.
  • Amazon WorkSpaces Applications now supports Windows Desktop OS — You can now bring your own Windows Desktop licenses to Amazon WorkSpaces Applications and stream full Windows desktops and applications from AWS-hosted dedicated hardware. BYOL eliminates OS fees (you pay only for compute and streaming infrastructure), supports eligible Microsoft 365 Apps for enterprise, and gives users a matching experience between local and remote environments — same workflows, shortcuts, and navigation in both.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

-Micah

Why Policy in Amazon Bedrock AgentCore chose Cedar for securing agentic workflows

Post Syndicated from Liana Hadarean original https://aws.amazon.com/blogs/security/why-policy-in-amazon-bedrock-agentcore-chose-cedar-for-securing-agentic-workflows/

Agents have agency: they adapt and find multiple ways to solve problems. This autonomy creates a fundamental security challenge: the large language model (LLM) at the heart of the agent is non-deterministic, and its decisions can’t be predicted or guaranteed in advance. It can hallucinate harmful actions with complete confidence. It’s vulnerable to prompt injection attacks, where adversaries inject malicious commands through tool responses or user inputs. LLMs don’t robustly differentiate between commands and data, everything is only tokens. For these reasons, if you want defense in depth, you must treat the LLM as an untrusted actor from a security point of view.

The insight is that the LLM can’t affect the external world directly: it has to go through an orchestrator that invokes tools based on the LLM’s output. This is precisely where the controls must be applied. What you need at this boundary is authorization: a decision about whether each tool invocation should be allowed and under what conditions. Consider a customer service agent for an online retailer. Without proper controls, it could process refunds that exceed authorized limits, apply discounts to product categories that should be excluded, or look up one customer’s data while handling another customer’s session.

If you control agents’ access to tools, you can establish a safety envelope within which the agent can operate freely. This differs from two common but unsatisfactory approaches:

  • Creating hard-coded workflows eliminates uncertainty, but by itself defeats the purpose of using an LLM as the brain of the agent, because you’ve built a traditional application with an LLM interface. And even with this restriction, using LLM outputs at any step can open up the same risks. While it’s a useful technique for well-understood workflows, it’s not sufficient for agents that need to adapt.
  • Human-in-the-loop provides a safety net for critical operations, and it will always have a role. But relying on it as the main control mechanism sacrifices autonomy and can lead to approval fatigue.

You need agents that are safe and autonomous. This requires an auditable, deterministic enforcement layer that sits outside the agent and tools. Why outside? Because the LLM’s plan is the thing you can’t trust—it can’t be responsible for enforcing its own constraints. Controls at the LLM layer—such as system prompts and training-time alignment—can be bypassed by prompt injection or hallucination. Hard-coded checks in agent or tool code are more robust, but become difficult to audit and manage at scale, especially when security logic is scattered across many tools and services. Centralizing authorization outside both gives you a single checkpoint the LLM can’t circumvent; one that’s auditable and can be verified independently of the application code.

This is where AgentCore Policies come in. Amazon Bedrock AgentCore Gateway sits between the agent and the remote tools it calls. When you associate a Policy with a Gateway, it blocks everything by default. Policies selectively open this boundary by specifying which tool invocations are allowed and under what conditions. This enforcement applies to all tool traffic routed through the Gateway. For this approach to scale, it must be more straightforward to reason about the policies than about the agent’s behavior.

AgentCore policies are expressed in Cedar. Cedar is an open source authorization policy language developed by AWS that has recently joined the Cloud Native Computing Foundation (CNCF). Cedar was designed with exactly these properties: it’s purpose-built for authorization, readable by humans, and analyzable by machines using automated reasoning. This gives enterprises the ability to scale policy definition and enforcement to their AI agents.

How Cedar is used by Amazon Bedrock AgentCore

Amazon Bedrock AgentCore provides the infrastructure to deploy and manage agents at scale. It includes AgentCore Runtime for hosting agents, AgentCore Gateway for managing how agents connect to tools using Model Context Protocol (MCP), and Policy in AgentCore. Policy intercepts all agent traffic through AgentCore gateways and evaluates each request against defined policies in the policy engine before allowing tool access. Cedar powers the policy layer.

AgentCore Policy uses Cedar and its mathematical analysis capabilities at several points in the AgentCore Gateway workflow: the Cedar authorization engine is used at policy evaluation and Cedar Analysis is used during policy authoring, and in the control plane.

Policy authoring: Developers can write Cedar policies directly or use natural language that gets translated to Cedar through a neuro-symbolic AI feedback loop. Neuro-symbolic AI combines machine learning’s flexibility with automated reasoning’s provable correctness. An LLM generates policies from natural language, while Cedar Analysis validates them using symbolic, mathematical reasoning. The following diagram illustrates this workflow:

Figure 1: Cedar policy generation workflow

Figure 1: Cedar policy generation workflow

An administrator specifies—in natural language—which MCP tools the agent can call and under what conditions. The neuro-symbolic feedback loop then formalizes this description into Cedar policies. Here’s how it works: first, the LLM translates the natural language into Cedar policies. These policies are then run through two stages of verification. In the first stage, AgentCore Policy uses a Cedar schema generator that takes the MCP tool descriptions and produces a Cedar schema. Cedar validates the policies against this schema, helping to ensure that they reference valid tools and parameters and ruling out whole classes of runtime errors. If validation passes, the second stage runs Cedar Analysis, which encodes each policy as a mathematical formula and detects issues like policies that grant or deny everything, or that contain impossible conditions. These mathematical proofs identify errors in the process of translating from the natural language description to Cedar policies, and guide corrections.

The neuro-symbolic feedback loop significantly improves the accuracy of the generated policies. This demonstrates the power of combining neural and symbolic approaches—the LLM provides creative translation from natural language, while automated reasoning provides rigorous validation.

Control plane: When attaching policies to an AgentCore Gateway, Cedar Analysis performs holistic analysis of the entire policy set. Instead of analyzing policies in isolation, it examines how they interact and their combined effect. This analysis identifies potential logical errors—such as conflicting or redundant policies—and detects whether the policy set produces unintended authorization outcomes. When Cedar Analysis detects these errors, the operation fails and returns a description of the issue, so the policy author can fix and retry. See the Formal analysis for policy verification section for examples of the checks.

MCP tool invocation enforcement: Each agent tool request made to the AgentCore gateway is evaluated against Cedar policies which determine whether the MCP tool invocation with the given arguments should be allowed. This creates the safety envelope while allowing the necessary bridges to enable the agent to perform its job.

MCP tool filtering: Cedar enables an additional layer of protection that operates before any tool invocation occurs. When an agent issues a list tools command, AgentCore Gateway uses Cedar’s partial evaluation capability to determine which actions would always be denied under the current policy set. Those actions are omitted from the list tool response. The agent and the underlying LLM never see those tool actions, eliminating an entire class of risk: the agent and LLM can’t attempt to invoke a tool it doesn’t know exists. This is a direct benefit of Cedar’s partial evaluation: the system can determine that certain tool actions are unreachable without needing to wait for an actual tool invocation attempt.

Why Cedar: Analyzability enables safety at scale

Natural language is too ambiguous for security-critical infrastructure, and general-purpose programming languages, like Python, are very expressive but too difficult to analyze. They can have unintended side effects, termination issues, and can be difficult to understand.

Cedar avoids these issues by excluding loops and stateful operations, so policy evaluation terminates in O(n) time in common cases. This bounded execution time means agents can make authorization decisions without disrupting user experience or workflow efficiency.

Cedar is straightforward to read. Regulatory compliance and security audits require policies that humans can understand and verify. Cedar policies read like structured natural language, making them accessible to security teams, compliance officers, and business stakeholders:

// Only allow bulk discounts for premium customers with sufficient quantity
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Platinum" &&
  context.input.orderQuantity >= 50
}
unless
{
  context.input
    .productTypes
    .containsAny
    (
      ["limited_edition", "seasonal_specials"]
    )
};

Auditors without a technical background can understand this policy: “Allow bulk discounts for platinum customers who order at least 50 items, except for limited edition or seasonal special products.” The unless clause makes the exception clear, which is how business rules are typically expressed in natural language. Notice that this single policy constrains two different sources of data. The customer tier comes from a JSON Web Token (JWT) claim—it can’t be hallucinated or manipulated by the LLM. The tool inputs like order quantity and product types, however, originate from the LLM’s tool call. Cedar policies constrain these inputs to only allowed values, ensuring that even if the LLM produces unexpected arguments, the policy enforcement layer rejects them deterministically.

Cedar is the right choice because it’s fast, straightforward to read, and analyzable through automated reasoning. This analyzability is why you can reason about the safety envelope around agents that’s expressed as Cedar policies. As agentic systems grow the number of tools grows. Without proper tooling, policy management becomes intractable; policies can conflict, create security gaps, or produce unintended authorization outcomes.

In the rest of this section, we examine how Cedar’s analyzability directly addresses this challenge through its deterministic, mathematically sound analysis. Because Cedar analysis can reliably detect conflicts and logical errors across large policy sets it enables scalable policy management through neuro-symbolic AI.

Formal analysis for policy verification

Cedar policies can be encoded as mathematical formulas and analyzed using automated reasoning techniques through a symbolic encoder. This enables AgentCore Policy to provide sophisticated policy verification capabilities during policy authoring and beyond. AgentCore Policy uses this analysis when authoring or attaching policies to detect possible logical errors, such as conflicting or redundant policies. Policy analysis, including policy comparison is available as an open source CLI tool. Next, we will take a look at some concrete examples of these checks.

Detecting logical errors in policies: Cedar Analysis can detect when policies contain logical errors. For example, the following policy has contradictory constraints that mean it can’t allow any request: the customer tier can’t be both gold and platinum at the same time. The intention was to use an || instead of &&, a mistake that can be made by both humans and AI systems that author policies.

// This policy cannot allow any requests due to logical errors
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  principal.getTag("customer_tier") == "Platinum"
}
unless { context.input.refundAmount > 1000 };

Similarly, Cedar Analysis can detect policies that always allow a given action, usually an indication of an overly permissive policy. For example, the following policy will allow all ApplyBulkDiscount requests because any order quantity will either be greater than or equal to 100 or less than 100.

// This policy allows all ApplyBulkDiscount requests
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  context.input.orderQuantity >= 100 ||
  context.input.orderQuantity < 100 ||
  (principal.hasTag("customer_tier") &&
   principal.getTag("customer_tier") == "Platinum")
};

Detecting such logical errors isn’t easy for humans, and can’t be done by pattern matching: you need the formal rigor of mathematical analysis, which is exactly what Cedar Analysis does.

Detecting policy conflicts: Cedar Analysis can also analyze the entire policy set to detect inconsistencies between different individual policies:

// These policies conflict - Analysis will detect the subtle issue
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  context.input.refundAmount < 100
};

forbid (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  ["Gold", "Platinum"].contains(principal.getTag("customer_tier")) &&
  context.input.refundAmount < 500
};

The permit policy allows gold customers to process refunds less than $100, while the forbid policy blocks gold customers (and platinum customers) from processing refunds less than $500. Because forbid overrides permit in Cedar, the forbid policy would block all gold customer refunds despite the permit policy.

Comparing policy changes: When updating policies, Cedar Analysis can also determine the exact impact of a change. Consider the following update to the unless clause (the policy lines with + have been added and those with - have been removed): we now block ApplyBulkDiscount only when the product type is limited_edition and the quantity exceeds 200.

 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ProcessRefund",
   resource
 )
 when
 {
   context.input.refundAmount < 500
 };
 
 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ApplyBulkDiscount",
   resource
 )
 when
 {
   context.input.orderQuantity >= 50
 }
 unless
 {
-  context.input.productTypes.containsAny(["limited_edition"])
+  context.input.productTypes.containsAny(["limited_edition"]) &&
+  context.input.orderQuantity > 200
 };

At first glance, adding a condition to the unless clause might seem more restrictive. In fact, it’s the opposite: narrowing when the unless applies means the permit now covers more requests. For example, an order of 73 units of a limited_edition product would have been blocked before but is now allowed. Cedar Analysis can automatically detect this and generates the following table showing the difference in permissiveness between the original policy set and the updated one:

Principal type

Action

Resource type

Status

OAuthUser

ProcessRefund

Gateway

Equivalent

OAuthUser

ApplyBulkDiscount

Gateway

More permissive

In the preceding example, the analysis tells us that the updated policy allows allows exactly the same ProcessRefund requests, but allows more ApplyBulkDiscount requests.

This formal verification capability is essential when agents operate autonomously and can affect the real world. Organizations need mathematical certainty that their policies will behave as intended.

Deterministic behavior for reliable governance

Unlike probabilistic AI models, enterprise security requires deterministic guarantees. Cedar policies always produce the same authorization decision for identical requests, regardless of evaluation order or system state. Cedar’s default deny, forbid wins, no ordering semantics help ensure predictable behavior.

// Policy evaluation order does not affect the authorization decision
permit(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.refundAmount < 500
};

forbid(
    principal,
    action == AgentCore::Action::"ProcessRefund", 
    resource
) when {
    context.input.orderDate.offset(duration("90d")) < context.system.now
};

Whether the permit or forbid policy is evaluated first, a refund request over $500 will always be denied, and any refund issued more than 90 days after the order date will also be denied. This predictability gives enterprises confidence in their agent governance.

From policies to production

By choosing AgentCore Policy and Cedar, organizations can deploy autonomous agents with policies they can reason about mathematically, not only hope the agents work correctly. Cedar’s combination of expressiveness, readability, and formal verification means that you can design agents with the flexibility needed to function and the certainty security teams demand.

Automated reasoning has already proven its value across AWS, from AWS IAM Access Analyzer verifying access policies to provable security for network configurations. Applying these same techniques to agentic AI is a natural extension: as agents take on more responsibility, the need for mathematically grounded guarantees only grows. The neuro-symbolic approach we’ve described in this post—combining LLM flexibility with the rigor of automated reasoning—points toward a future where agents can be both more autonomous and more trustworthy, because the verification keeps pace with the autonomy.

Learn more

Policy is now available as part of Amazon Bedrock AgentCore Gateway. To learn more about Cedar and its capabilities, visit the Cedar website, try the Cedar playground, or join the Cedar community on Slack.

For more information about Policy in Amazon Bedrock AgentCore Gateway, visit the AWS documentation or explore the AgentCore Gateway console.

If you have feedback about this post, submit comments in the Comments section below.

Liana Hadarean

Liana Hadarean

Liana is a Principal Applied Scientist at AWS. She has worked on the code analysis tools that power Amazon Q Java security detectors, and is now a contributor to the Cedar policy language.

John Tristan

Jean-Baptiste Tristan

Jean-Baptiste is a Senior Principal Applied Scientist at AWS Agentic AI where he works on neurosymbolic AI and agentic safety.

AWS Weekly Roundup: AWS Transform at 1 year, Claude Platform on AWS, EC2 M3 Ultra Mac instances, and more (May 18, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-transform-at-1-year-claude-platform-on-aws-ec2-m3-ultra-mac-instances-and-more-may-18-2026/

Just a year ago, we launched AWS Transform for .NET, Mainframe and VMware workloads, the first agentic AI service purpose-built for modernizing enterprise applications at scale. At re:Invent 2025, we introduced AWS Transform custom, which enables organizations to modernize and transform code at scale using AWS-managed and custom transformations. You can upgrade language versions, migrate frameworks, optimize performance, and analyze code bases using transformations that are ready to use or can be customized to meet your organization’s specific requirements. We also introduced full-stack Windows modernization capabilities and Reimagine capabilities and automated testing functionality for mainframe.

In 12 months, thousands of customers migrated hundreds of thousands of servers, saved 1.6+ million hours, and processed 4.5+ billion lines of code with AWS Transform. Celebrating its 1-year anniversary, AWS Transform agents now available in Kiro, Claude, Cursor, and Codex, including the agent builder toolkit Kiro power for building customized transformation agents.

To learn what happened in 12 months, the four things we learned, and how that evolved our roadmap, visit the one-year anniversary blog post.

Last week’s launches
Here are last week’s launches that caught my attention:

  • The general availability of Claude Platform on AWS – You can get direct access to Anthropic’s native Claude Platform experience, including APIs, console, and early-access beta features, directly through your existing AWS account, without managing separate accounts, billing, or tracking. Claude Platform on AWS is operated by Anthropic, and customer data is processed outside the AWS security boundary. To learn more, visit the deep dive blog post.
  • Amazon EC2 M3 Ultra Mac instances – These instances are built on Apple M3 Ultra Mac Studio computers featuring a 28-core CPU, 60-core GPU, 32-core Neural Engine, and 256GB of unified memory. Compared to EC2 M4 Max Mac instances, M3 Ultra Mac instances provide 2x the unified memory, 1.75x the CPU cores, 1.5x the GPU cores, and 2x the Neural Engine cores, giving Apple developers the headroom to run significantly more Xcode simulators in parallel and accelerate on-device ML workflows to improve product time to market.
  • Amazon Redshift RG instances powered by AWS Graviton – These instances deliver better performance, running data warehouse and data lake workloads up to 2.4x as fast as previous generation RA3 instances, at 30% lower price per vCPU. RG instances include Redshift’s custom-built vectorized data lake query engine that processes Apache Iceberg and Parquet data on your cluster nodes.
  • Amazon Bedrock Advanced Prompt Optimization – You can optimize your prompts for any model on Bedrock, while comparing your original prompts to your optimized prompts across up to 5 models simultaneously. You can also use this if you are migrating to a new model or just want to get better performance on your current model.
  • AWS Security Agent full repository code scanning (preview) – You can use a new capability in AWS Security Agent that performs deep, context-aware security analysis of your entire codebase. When vulnerabilities are found, the scanner generates code remediation—specific fixes tied to the exact file and line—enabling teams to remediate security vulnerabilities faster than ever before. This capability is available at no additional charge for existing AWS Security Agent customers during the preview.
  • AWS Interconnect – multicloud connectivity with Oracle Cloud Infrastructure (preview) – You can quickly provision resilient, scalable private connections to other cloud providers using AWS Interconnect – multicloud connectivity. OCI is the latest CSP to adopt the open specification that powers AWS Interconnect. This allows AWS to provide a consistent, simple experience to our customers on OCI (preview), Google Cloud (generally available), and Microsoft Azure (coming later in 2026).

Additional updates
Here are some additional news items that you might find interesting:

  • Accelerate AI research and education with Build on Trainium program – Read how the next generation of AI researchers is using Amazon chips to accelerate discovery. AWS invested $110 million to give university researchers access to purpose-built AI chips. AWS Trainium is speeding up AI research at UC Berkeley, MIT, Carnegie Mellon, and more. All research is open source, meaning improvements flow back to the broader developer community.
  • A full list of AWS Community Days 2026 – There’s something different about an event where the speakers are your peers, the organizers are volunteers who do this out of passion, and the agenda was shaped by the community itself. That’s exactly what AWS Community Days are, and they’re happening in cities across every continent, every year.
  • The Kiro Startups Credit program is back – Thousands of founders applied in the first round, and now applications are open again. Apply to receive up to one year of Kiro Pro+ credits automatically applied to your organization’s AWS account.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events including AWS Summits. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Building Self-Extending CLI Tools with Strands Agent

Post Syndicated from Ragib Ahsan original https://aws.amazon.com/blogs/devops/building-self-extending-cli-tools-with-aws-strands/

I. Introduction

Engineering teams build internal command-line interface (CLI) tools because repetitive operational tasks such as generating reports, auditing infrastructure, and checking service health are faster and more reliable when automated behind a consistent interface. A well-built CLI replaces ad-hoc scripts with structured commands, standardized error handling, and composable workflows that any team member can run. However, building these tools follows a predictable development lifecycle. The developer sets up a package, writes commands, handles errors, and ships it, then spends the next six months as its sole maintainer. Meanwhile, requests for new commands, custom report formats, and one-off integrations pile up as other teams across the organization discover the tool is useful for their workflows too. Frameworks like Click and Typer reduce the friction, but every new command still needs to be written, tested, and deployed manually.

Tools that generate their own capabilities on demand offer a different approach. Instead of writing each command manually, users can describe what is needed in natural language, and the tool writes the code, loads it, and makes it available at runtime without requiring a restart or redeployment. This is called meta-tooling, a repeatable pattern for giving applications the ability to create their own tools dynamically. For teams that maintain growing collections of internal utilities, this eliminates the bottleneck of having a single developer write every new feature.

In this post, we will walk through one implementation of this pattern, a CLI generator called CLI Creator. CLI Creator combines three technologies into a mechanism that organizations can adapt for their own use cases:

  • Amazon Bedrock, a fully managed service for building generative AI applications with foundation models, with Anthropic’s Claude Opus 4.6 for AI-powered code generation.
  • Strands Agents SDK, an open-source Python framework for building AI agents with tool use, for dynamic tool creation, loading, and execution at runtime.
  • Model Context Protocol (MCP), an open standard for connecting AI applications to external data sources and tools, for automatically discovering API servers that give generated tools additional knowledge.

The result is a development workflow where new CLI capabilities go from request to working command in minutes instead of days, without manual coding. By the end of this post, a single natural language prompt will have produced a complete, installable CLI. That CLI can extend itself with new tools, refine them iteratively, and discover relevant MCP servers through an interactive selection workflow.

II. Solution Overview

The Challenge

As an example, consider a platform engineering team that produces weekly operations reports for leadership. Every Monday morning, stakeholders expect a summary of their AWS footprint, including which Amazon DynamoDB tables are running hot, which Amazon Simple Storage Service (Amazon S3) buckets are growing fastest, and who made significant infrastructure changes last week. The AWS CLI can list tables and buckets, but it cannot produce these reports.

Each report is a multi-step workflow that involves calling several APIs, joining the data, computing derived metrics like estimated monthly cost or growth rate, and formatting the output for a specific audience. The team ends up writing Python scripts for each report, and every new report request means another script by a developer.These are each their own small project, often requiring a hundred lines of Python to pull multiple APIs, compute derived metrics, and format output before you even think about error handling. Requirements shift weekly, so each change means modifying source code, testing, and redeploying. The tooling never converges; the team ends up with a folder of disconnected scripts, each with its own argument parsing, error handling, and output formatting. Any team that builds small, purpose-built utilities faces the same friction, and operations reporting is the example we use to illustrate the meta-tooling pattern.

The Solution

Prerequisites

To follow along with this post, you will need:

  • Python 3.12 or later
  • An AWS account with Amazon Bedrock access enabled for Anthropic Claude models in us-west-2
  • AWS credentials configured locally (via `aws configure` or environment variables)
  • Git installed (for tool version tracking)

The source code is available on GitHub. Installation instructions are in the repository README.

Walkthrough

Instead of writing report scripts manually, organizations describe what they need in natural language.Terminal screenshot of a CLI Creator tool generating an AWS operations reporting CLI called "aws-ops-reporter." The tool analyzes requirements, detects API keywords (DynamoDB, S3, CloudTrail), and displays 18 available MCP servers. The user selects servers 1, 9, and 18 (AWS DynamoDB, AWS S3, AWS CloudTrail). A planned CLI structure shows four commands: dynamo-capacity, unused-s3, audit-cloudtrail, and cost-summary. A confirmation prompt reads "Proceed with generation? [Y/n].

The system then does the following:

  1. Claude Opus 4.6 on Amazon Bedrock analyzes the description and extracts a structured list of commands, arguments, and options.
  2. MCP servers are discovered automatically, wherein the system detects keywords like “DynamoDB”, “S3”, and “CloudTrail” in the description, searches the MCP registry for relevant API servers, and presents an interactive selection prompt for choosing which servers to include.
  3. Once the user confirms, the system generates complete Python code for each command. These are not stubs or placeholders that users may typically see within generated code, but working implementations with validated AWS SDK for Python (Boto3) calls, error handling, and type hints.
  4. Finally, the output is packaged as an installable Python project with a pyproject.toml file and entry points configured.

Most importantly, the generated CLI includes a tool command group that enables self-extension at runtime. After installation, users can ask the CLI to create entirely new reporting tools and iteratively refine them without touching source code. This is the repeatable part of the pattern because any generated tool inherits the ability to extend itself. This mechanism is built into every generated CLI, so each one is immediately capable of growing beyond its original scope.

III. Technical Implementation

Strands Agents SDK Integration

The Strands Agents SDK is the backbone of the meta-tooling pattern. It provides three features that make self-extending tools possible, and these features are not specific to CLI generation. Any Python application can use them to dynamically create and manage capabilities at runtime.

The @tool Decorator

When a user asks a generated CLI to create a new tool, Claude Opus 4.6 on Amazon Bedrock produces Python code that uses the Strands @tool decorator. This decorator registers the function with Strands’ tool system, making it immediately discoverable and executable:

from strands import tool

@tool 
def list_s3_buckets_with_costs() -> List[Dict[str, Any]]:

The @tool decorator registers the function’s signature, type hints, and docstring as a tool specification that the Strands Agent can reason about and invoke.

Runtime Tool Loading

The Strands Agents SDK includes a tool loading system that can discover and import @tool-decorated functions from Python files at runtime. Tools do not need to be registered at application startup. They can be created, saved to a directory, and made available to the agent dynamically.In our implementation, generated tools are saved as standalone Python files in a directory called `tools/`. Each time a CLI command runs, the application scans this directory, loads any @tool-decorated functions it finds, and adds them to the agent’s tool collection without requiring a restart.The self-extending pattern works because of this scan-on-invocation approach. A user can create a tool, execute it, decide it needs changes, update it, and execute again without any rebuild or reinstall step since each CLI invocation discovers and loads whatever tools exist on disk.

Agent Orchestration with BedrockModel

The Strands Agent class ties everything together. It connects to Amazon Bedrock via BedrockModel and manages a collection of tools:

from strands import Agent
from strands.models import BedrockModel

agent = Agent(
    model=BedrockModel(
        model_id=""
    ),
    tools=[shell_tool, editor_tool] + loaded_tools,
    system_prompt="You are a tool creation assistant..."
)

When the agent receives a tool creation request, it calls Amazon Bedrock to generate the implementation and saves it as a Python file in the tools/ directory. The next CLI command automatically discovers and loads the new tool.

Amazon Bedrock Integration

CLI Creator connects to Anthropic’s Claude through Amazon Bedrock’s cross-region inference profile. Amazon Bedrock serves two distinct roles in the system.

Role 1: CLI Requirements Analysis with Structured Output

When you run cli-creator create, the first step is analyzing the natural language description and extracting a structured specification. Instead of parsing raw text from the model, we use the Strands Agents SDK’s structured output feature with Pydantic models to guarantee the response conforms to our schema:

from pydantic import BaseModel, Field
from strands import Agent
from strands.models import BedrockModel

class CommandSpec(BaseModel):
    name: str = Field(description="Command name in kebab-case")
    description: str = Field(description="What this command does")
    arguments: Optional[List[str]] = Field(default_factory=list)
    options: Optional[List[CommandOption]] = Field(default_factory=list)

class CLIRequirements(BaseModel):
    cli_name: str = Field(description="CLI name in kebab-case")
    description: str = Field(description="One-line description")
    commands: List[CommandSpec] = Field(description="Commands to generate")
    dependencies: List[str] = Field(default_factory=list)

# Create agent and invoke with structured output
agent = Agent(
    model=BedrockModel(model_id="us.anthropic.claude-opus-4-6-v1"),
    system_prompt="You are an expert CLI designer..."
)

result = agent(
    f"Analyze this CLI description: {description}",
    structured_output_model=CLIRequirements
)

# Access the validated Pydantic model — no JSON parsing needed
requirements: CLIRequirements = result.structured_output

By passing the structured_output_model, the Strands Agent constrains the model’s response to match the Pydantic schema. The result is a validated Python object where if the model’s first attempt does not conform to the schema, Strands automatically sends the validation errors back to the model and retries, producing a correct response without manual intervention. This approach eliminates malformed JSON, missing fields, wrong types, and hallucinated structure.

Role 2: Complete Command Generation with AI Functions

The second Amazon Bedrock role is generating complete command implementations. Direct integration of AI agents in code generation workflows is often avoided because of the model’s non-deterministic nature. There is no guarantee that generated code will compile, follow the expected structure, or avoid common pitfalls like empty error handlers. Strands AI Functions addresses this through runtime post-condition checking. AI Functions is a Python library for building reliable AI-powered applications through a new abstraction of functions that behave like standard Python functions but are evaluated by reasoning AI Agents. You decorate a function with @ai_function, write its prompt as a docstring with curly-brace placeholders, and attach post-conditions that the output must satisfy. If any post-condition fails, AI Functions automatically initiates a self-correcting loop, sending the specific error back to the model and retrying until all conditions pass or the maximum attempts are reached.

We use AI Functions to build a self-correcting code generation pipeline. Each generated command must pass three post-conditions before it is accepted:

from ai_functions import ai_function, PostConditionResult

def check_syntax(response: str) -> PostConditionResult:
    try:
        compile(response, '<generated>', 'exec')
        return PostConditionResult(passed=True)
    except SyntaxError as e:
        return PostConditionResult(
            passed=False,
            message=f"Python syntax error on line {e.lineno}: {e.msg}. Fix: {e.text}"
        )

def check_has_decorator(response: str) -> PostConditionResult:
    if '@cli.command' in response:
        return PostConditionResult(passed=True)
    return PostConditionResult(
        passed=False,
        message="Missing @cli.command() decorator."
    )

@ai_function(
    post_conditions=[check_syntax, check_has_decorator, check_no_empty_try],
    max_attempts=3
)
def generate_click_command(command_name: str, description: str, ...) -> str:
    """
    Generate a complete Click CLI command function in Python.

    Use @cli.command() decorator. Include needed imports using 'from X import Y' style.
    Always use 'import click' and reference as click.echo(), click.style().

    Command: {command_name}
    Description: {description}
    """

The @ai_function decorator turns the function’s docstring into a prompt template. Curly-brace placeholders like {command_name} are filled from the function arguments at call time. Each post-condition receives the model’s response and returns a PostConditionResult. When a condition fails, AI Functions sends the error message back to the model and retries automatically, up to max_attempts. The model sees the specific failure (“syntax error on line 42”, “missing @cli.command decorator”, “empty try/except block detected”) and corrects it on the next attempt.

The prompt embedded in the docstring still enforces coding conventions (use import click rather than from click import, use from X import Y for all other imports) to prevent import conflicts. Post-conditions catch what the prompt misses, making the pipeline significantly more reliable than prompt engineering alone.

MCP Server Discovery and Integration

The Model Context Protocol adds automatic discovery of external API knowledge to the pattern. When your tool description mentions AWS services, the system searches for MCP servers that can provide domain-specific tooling. Generated tools can tap into live, structured API knowledge beyond what Amazon Bedrock knows at generation time.

How Discovery Works

The system uses Amazon Bedrock to extract API keywords dynamically. The api_keywords field is part of the same CLIRequirements Pydantic model used for structured output, so keyword detection happens in the same call that extracts commands and dependencies at zero additional cost:

class CLIRequirements(BaseModel):
    cli_name: str = ...
    commands: List[CommandSpec] = ...
    dependencies: List[str] = ...
    api_keywords: List[str] = Field(
        default_factory=list,
        description="API/service keywords to search for MCP servers"
    )

When the model returns keywords like ["dynamodb", "s3", "cloudtrail"], the system uses a Strands Agent with the http_request tool from Strands Agents Tools to search the MCP registry for each keyword. Results are merged and deduplicated.

Interactive MCP Selection

After discovering relevant MCPs, the system presents them to the user for selection:

Terminal screenshot showing an AI-powered MCP server discovery process. The tool analyzes requirements, detects API keywords (DynamoDB, S3, CloudTrail), searches for relevant servers, and displays 18 available MCP servers in a numbered list. The user selects servers 1, 9, and 18 at a prompt, confirming the inclusion of AWS DynamoDB, AWS S3, and AWS CloudTrail.

Selected MCPs are configured in the generated CLI’s .mcp.json file, and a bridge module is copied to the output project. This bridge connects to MCP servers at runtime, extracts their tool metadata, and converts them into Strands @tool functions that the Agent can invoke.

Terminal screenshot showing CLI code generation in progress. The user confirms generation with "y." Command 1/5 (dynamo-capacity) succeeds with 9,181 characters generated. Command 2/5 (unused-buckets) fails validation due to a missing @cli.command() decorator, retries (attempt 1/3), and ultimately succeeds with 8,834 characters. Command 3/5 (audit-changes) begins generating.

After MCP selection, CLI Creator generates each command sequentially using AI Functions. Here, the unused-buckets command initially fails the check_has_decorator post-condition for missing the @cli.command decorator, and AI Functions automatically retries generation with the error fed back to the model, producing valid code on the second attempt. All commands go through this process before having an installable CLI.

The Meta-Tooling Workflow: Create, Update, Revert

The most distinctive feature of the pattern is the iterative tool refinement workflow. This is where meta-tooling becomes practical, and it is the part most easily adapted to domains beyond CLI generation.

Step 1: Install and verify the generated CLI

Terminal screenshot showing successful CLI tool generation. A green checkmark with green text confirms "CLI tool generated successfully!" A yellow warning notes "External dependencies detected!" followed by installation instructions: navigate to the generated/aws-ops-audit directory, install dependencies with pip, and verify with the --help command.

After generation completes, install the CLI and verify it works:

Terminal screenshot showing the help output for the "aws-ops-audit" CLI tool, run inside a Python virtual environment (test-venv). The tool is described as "An AWS operations reporter that checks DynamoDB capacity, lists unused S3 buckets, and audits CloudTrail changes." Two options (--version, --help) and six commands (audit-trail, check-capacity, configure, full-report, tool, unused-buckets) are listed.

Each command is fully implemented. Here is unused-buckets pulling live S3 data:

Terminal screenshot showing the output of the "aws-ops-audit unused-buckets" command run in a Python virtual environment. An "Unused S3 Buckets Report" lists four S3 buckets with metadata including name, region, object count, size, last modified date, creation date, and reason for being flagged — either "no activity since [date]" or "empty bucket."

After installation, the CLI is ready to use. Each subcommand supports --help for detailed parameter information.

Step 2: Create a new reporting tool at runtime

Consider a scenario where leadership requests a new report that was not part of the original CLI, such as a summary of all Amazon S3 buckets with their sizes, sorted by cost impact. Instead of modifying source code, use the built-in tool create command:

Terminal screenshot showing the output of the "aws-ops-audit unused-buckets" command run in a Python virtual environment. An "Unused S3 Buckets Report" lists four S3 buckets with metadata including name, region, object count, size, last modified date, creation date, and reason for being flagged — either "no activity since [date]" or "empty bucket."

Amazon Bedrock generates a complete Strands tool, saves it to `tools/`, and commits it to git. The next CLI command automatically discovers and loads the new tool from disk, so you can execute it right away:

Terminal screenshot showing the output of "aws-ops-audit tool execute list_s3_buckets_by_cost_impact." A summary section displays aggregate statistics for 26 S3 buckets totaling 3.99 GB and $1.10/year in estimated costs. Below, a detailed data table ranks all 26 buckets by cost impact, showing columns for bucket name, cost rank, cost tier (MINIMAL or EMPTY), creation date, estimated monthly/annual costs, object count, region, and size metrics.

Output is automatically formatted based on data type, so lists of dictionaries render as tables, single dictionaries display as key-value pairs, and everything else falls back to JSON.

Step 3: Update and review changes

Suppose the initial output needs adjustment. Leadership wants the report to exclude buckets with an object count of zero. The user describes this change in natural language using the tool update command.

Terminal screenshot showing the update of the "list_s3_buckets_by_cost_impact" tool using the aws-ops-audit CLI with the instruction to "exclude buckets with zero objects." The tool is updated via Bedrock AI analysis, versioned with git, and a git diff displays changes to the function's docstring — adding exclusion behavior documentation and new return fields (total_buckets_scanned, excluded_empty_buckets).

CLI Creator commits the current version to git before overwriting, then generates a new version. The tool diff command shows exactly what changed. Now execute the updated tool to see the improvements:

Terminal screenshot showing the updated output of "aws-ops-audit tool execute list_s3_buckets_by_cost_impact" after the zero-object exclusion update. Summary statistics now show 22 active buckets out of 26 scanned, with 4 empty buckets excluded. The data table lists only 22 rows, all classified as MINIMAL — confirming the empty bucket exclusion is working correctly.

The same update workflow applies regardless of what the tool does, whether it is an Amazon S3 cost report, an Amazon DynamoDB capacity analyzer, or a Salesforce data exporter.

Step 4: Revert if needed

If the update didn’t work as expected, tool revert restores the previous version from git:

Terminal screenshot showing the revert of the "list_s3_buckets_by_cost_impact" tool using the aws-ops-audit CLI. A confirmation prompt asks "Revert 'list_s3_buckets_by_cost_impact' to previous backup? [Y/n]:" and the user enters "y." A green checkmark confirms "Tool reverted!" followed by a note: "Restored from git history."

The git log shows the full history of create, update, and revert operations, all tracked automatically.

Terminal screenshot showing a two-line git log output. The most recent commit (ef4a65e, HEAD → main) reverts the list_s3_buckets_by_cost_impact tool. The previous commit (3640bde) updated the same tool to "exclude buckets with zero objects and add a total."

Under the hood, tool create, tool update, and tool revert are convenience wrappers around git. Each operation commits to the repository, so the version history is standard git and works with any existing workflow. The tool diff and tool revert commands exist so that someone iterating conversationally can see changes and undo them without switching context to git commands, but git log, git diff, and git revert work just as well. Git-based versioning and one-command reverts make it safe to experiment.

Step 5: Output formats

Reports often need to be consumed in different ways. The --format flag lets you control how output is rendered:

Terminal screenshot showing a two-line git log output. The most recent commit (ef4a65e, HEAD → main) reverts the list_s3_buckets_by_cost_impact tool. The previous commit (3640bde) updated the same tool to "exclude buckets with zero objects and add a total."

The formatter attempts to use the Rich library for colored tables when available and falls back to an ASCII table implementation when it is not installed. Here is a new AWS Lambda tool stored in `tools/`, rendering as a table by default:

Terminal screenshot showing the creation and immediate execution of a new "list_lambda_functions_by_code_size" tool using the aws-ops-audit CLI. The tool is created from a natural language description, then executed to produce a Lambda functions report for us-east-1 showing 11 functions with a total code size of 206.31 MB, displayed in a table sorted by code size descending.

IV. Conclusion

The meta-tooling pattern demonstrated here combines Amazon Bedrock for code generation, the Strands Agents SDK for runtime tool management, and Model Context Protocol for external API discovery into a system where CLIs extend themselves through natural language. The implementation has clear limitations today. Generated code still requires human review before production use; post-conditions catch structural errors but cannot verify business logic correctness, and the MCP ecosystem is young enough that server coverage is uneven across domains.

V. Next Steps

CLI tools are a natural starting point because they have a well-defined structure and fast feedback loops, but the same mechanism applies to any software that could benefit from generating and refining small, composable units of functionality at runtime. Infrastructure-as-code modules, data pipeline transformations, API integration adapters, and compliance policy checks are all domains where the creation pattern is repetitive, and the validation criteria are expressible as post-conditions. To explore the pattern:

– Start with Amazon Bedrock for foundation model access.

– Use the Strands Agents SDK for tool orchestration.

– Browse the MCP ecosystem at mcpservers.org.

– Fork the CLI Creator source code on GitHub.


About the authors

Ragib Ahsan

Ahsan is an AI Acceleration Architect at Amazon Web Services (AWS), where he helps organizations build and implement AI/ML solutions. Specializing in computer vision and industrial manufacturing, he works with AWS partners and engineering teams to create practical applications using cloud technologies.

Amazon Bedrock introduces new advanced prompt optimization and migration tool

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-bedrock-introduces-new-advanced-prompt-optimization-and-migration-tool/

Today, we’re announcing Amazon Bedrock Advanced Prompt Optimization, a new tool that you can use to optimize your prompts for any model on Amazon Bedrock, while comparing your original prompts to optimized prompts across up to 5 models simultaneously. With the new prompt optimization, you can migrate to a new model or improve performance from your current model. You can test them to make sure they see no regressions on known use cases and also improve on underperforming tasks.

The new prompt optimizer takes in your prompt template, example user inputs for the variable values, ground truth answers, and an evaluation metric to use as a guide. You can even use this with multimodal user inputs – it supports png, jpg, and pdf as inputs to your prompt templates so you can optimize prompts for tasks like document and image analysis.

You can also provide an AWS Lambda function, LLM-as-a-judge rubric, or a short natural language description to guide the optimization. The prompt optimizer works in a metric-driven feedback loop to optimize the prompt and resulting model responses for the evaluation metric, and outputs the original and final prompt templates with evaluation scores, cost estimates, and latency.

Bedrock Advanced Prompt Optimization in action
To get started with the new prompt optimization, choose Create prompt optimization on the Advanced Prompt Optimization page of Amazon Bedrock console.

Pick up to 5 inference models for which to optimize your prompts. You can use this if you are migrating to a new model or just want to get better performance on their current model. If you’re changing models, you can select your current model as a baseline and up to 4 other models. If you aren’t changing models, then just select your current model to see before and after optimization.

You should prepare your prompt templates in JSONL format with example user data, ground truth answers, and an evaluation metric or rewriting guidance. For .jsonl files, each JSON object must be on a single line.

{
    "version": "bedrock-2026-05-14",           // required; Fixed value
    "templateId": "string",                    // required
    "promptTemplate": "string",                // required
    "steeringCriteria": ["string"],            // optional
    "customEvaluationMetricLabel": "string",   // required if customLLMJConfig or evaluationMetricLambdaArn is used
    "customLLMJConfig": {                      // optional
        "customLLMJPrompt": "string",          // required if customLLMJConfig present
        "customLLMJModelId": "string"          // required if customLLMJConfig present
    },
    "evaluationMetricLambdaArn": "string",     // optional
    "evaluationSamples": [                     // required
        {
            "inputVariables": [                // required
                {
                    "variableName1": "string",
                    "variableName2": "string"
                }
            ],
            "referenceResponse": "string"      // optional
            "inputVariablesMultimodal": [      // optional
                {
                "Arbitrary_Name": {            // required for your multimodal variable.
                    "type": "string",          // choose from "PDF" or "IMAGE". Acceptable filetypes for IMAGE = png, jpg,  
                    "s3Uri": "string"          // input the S3 path of the file
                }
            ]
        }
    ]
}

You can upload files directly or import prompt templates from Amazon Simple Storage Service (Amazon S3) and set an S3 output location where prompt optimization results and evaluation data will be stored. Then, choose Create optimization.

Amazon Bedrock automatically sends your prompt templates and example data with optional ground truth to your inference models, evaluates the responses with your evaluation metric, then rewrites the prompt in a feedback loop to optimize it for your inference models. You’ll see evaluation results based on your provided metric and your final optimized prompts.

As you noted, you can evaluate prompt quality in three ways: a Lambda function with your own Python scoring logic, LLM-as-a-Judge with a custom rubric, or natural-language steering criteria. You can just choose one per prompt template, but can do multiple prompt templates in a job, so they can use a different method for each prompt template if they want.

  • Lambda function — If you have a concrete metric (accuracy, F1, execution accuracy, structured-JSON match, etc.), you can deploy a Lambda function containing your custom scoring logic and configure evaluationMetricS3Uri field of the prompt template. Inside the Lambda, the core is a compute_score implementation that programmatically compares model outputs against reference responses.
  • LLM-as-a-Judge — If your task is open-ended (summarization, generation, reasoning explanations) and you want a rubric-based score, you can configure the S3 config file in the customLLMJConfig field of the prompt template to define named metrics with structured instructions and a rating scale. A Bedrock judge model evaluates each prompt-response pair and returns a score with reasoning. The default model is Claude Sonnet 4.6 and you can also select your own from a list of judge models.
  • Steering criteria — If you know the qualities you want (brand voice, format, safety constraints) but don’t want to author a full judge prompt, you can define criteria in the input dataset through the steeringCriteria array of the prompt template. Instead of structured metrics with rating scales, you provide free-form natural language criteria that the LLM judge evaluates holistically. If you use this option, then a default LLM-as-a-judge prompt will evaluate the responses and incorporate your steering criteria into the judge prompt. The judge model in this case is Anthropic Claude Sonnet 4.6.

To learn more about how to use the advanced prompt optimization and migration, visit the advanced prompt optimization in Bedrock guide and the sample codes in Github.

Now available
Amazon Bedrock Advanced Prompt Optimization is available today in US East (N. Virginia, Ohio), US West (Oregon), Asia Pacific (Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Zurich), and South America (São Paulo) Regions. You are charged based on the Bedrock model-inference tokens consumed during optimization, at the same per-token rates as regular Bedrock inference. To learn more, visit the Amazon Bedrock pricing page.

Give the advanced prompt optimization a try in the Amazon Bedrock console or with CreateAdvancedPromptOptimizationJob API today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

Agentic application modernization at scale with Strands and Amazon Transform custom

Post Syndicated from Kanishk Mahajan original https://aws.amazon.com/blogs/devops/use-generative-ai-agents-for-application-modernization-at-scale-with-strands-amazon-transform-custom-and-amazon-bedrock-agentcore/

Introduction

Modernizing applications by upgrading language runtimes, migrating SDKs, and refactoring frameworks is important for cloud adoption but can be labor-intensive at scale. Each repository requires analysis of dependencies and transformation needs; custom transformation logic must be built and validated, and changes are often executed sequentially across codebases. If you have hundreds of applications, this stretches timelines from months to years, while introducing inconsistency across your teams.

To address this, Amazon Web Services (AWS) provides a composable set of building blocks. AWS Transform custom enables reusable, CLI-driven code transformations for upgrading runtimes, SDKs, and frameworks consistently across large portfolios. Strands Agents provides a framework for building multi-agent systems that coordinate complex transformation workflows. Amazon Bedrock AgentCore delivers the managed runtime, memory, and observability to operate these agents reliably in production. Together, they replace manual, sequential modernization with an intelligent, automated approach that scales.

In this post, we show you how to combine these services to build a generative AI–powered, agentic modernization system that can automatically analyze application repositories, determine required changes, create missing transformations, and execute them in parallel at scale.

Solution overview

The solution uses an agentic architecture that separates intelligent decision-making from deterministic execution, enabling automation at scale while maintaining consistency and control. In this post, you will build an AI-driven application modernization system that demonstrates how multi-agent workflows can be applied to large-scale code transformation scenarios. You interact with the system through a React-based frontend or API interface, submitting individual repositories or batch workloads via CSV inputs. Requests are processed asynchronously through an API layer that invokes an orchestrator agent running on Amazon Bedrock AgentCore, which coordinates specialized agents to analyze codebases, identify transformation requirements, and manage execution workflows. Results are stored and surfaced through the interface, allowing users to track progress and review outputs in real time.The workflow begins with repository analysis, where the system inspects application codebases to identify languages, dependencies, and required upgrades such as runtime version changes or SDK migrations. Based on this analysis, the system maps each application to an existing transformation when available. If no suitable transformation exists, a creation agent dynamically generates one using natural language instructions and publishes it to a centralized registry for reuse, creating a continuously improving system where transformation coverage expands over time.

Once transformations are identified or created, an execution agent runs them at scale by invoking AWS Batch jobs that execute the AWS Transform custom CLI, enabling parallel processing across multiple repositories. The orchestrator coordinates all agents, maintains workflow state using Amazon Bedrock AgentCore Memory, and ensures reliable execution through structured task decomposition, tool invocation, and error handling. While the example focuses on application re-platforming, the same architectural pattern can be applied to other large-scale code analysis and automation workflows.

The following architecture diagram (Figure 1) illustrates the various components of our solution as outlined in this section:architecture diagram describing the multi agent strands and agentcore deployment

Figure 1: AWS Transform custom Agentic Orchestration Architecture using Strands agents and Amazon Bedrock AgentCore

Prerequisites

Complete the following prerequisites:

  1. Install the AWS Command Line Interface (AWS CLI).
  2. Install the AWS SAM CLI v1.100.0+
  3. Install Docker v20.x+.
  4. Install Node.js v18.x+
  5. Install Python v3.11+
  6. Install the AWS CDK CLI
  7. Enable access to a Bedrock model for the orchestrator in your deployment region. The default model can be configured through the Amazon Bedrock model access console. To use a different model, set `BEDROCK_MODEL_ID` in `deployment/config.env` before Step 3 and enable access to that model instead. Model access approval can take a few minutes in some accounts, so complete this step before deploying.

Dependencies

The Strands Agents implementation has the following dependencies that are packaged in the DockerFile:

  1. Strands multi-agent framework: strands-agents
  2. Strands agent tools and utilities: strands-agents-tools
  3. HTTP library for API calls: requests
  4. Amazon Bedrock AgentCore SDK: bedrock-agentcore
  5. AWS SDK for Python: boto3

Deploy the solution

The solution is available for download on the GitHub repo. This post walks through the CDK + SAM deployment path (Option A in the repository README). The repository also includes a CDK-only option (Option B); see the repository README for details.

Step 1: Clone the repository

git clone https://github.com/aws-samples/aws-transform-custom-samples.git

cd aws-transform-custom-samples/agentic-atx-platform

Step 2: Configure AWS Credentials

# Configure AWS CLI

aws configure

# Verify credentials

aws sts get-caller-identity

Step 3: Deploy ATX CLI Container image and frontend using AWS CDK

# Copy configuration template (defaults work for most setups; edit only to change region or Bedrock model)

cd deployment

cp config.env.template config.env

# Authenticate with Amazon ECR Public (required for the Docker base image pull)

aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin public.ecr.aws

# Build the UI placeholder so CDK’s UI stack has ui/dist/ to deploy

cd ../ui && npm install && npx vite build

# Install CDK dependencies and bootstrap (run once per account/region)

cd ../cdk

npm install cdk bootstrap

# Build TypeScript and deploy the three stacks

npx tsc

CDK_DEFAULT_ACCOUNT=$(aws sts get-caller-identity --query Account --output text)

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

# Note for accounts without a default VPC , pass the VPC context flags to `cdk deploy`:

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never

cdk deploy AtxContainerStack AtxInfrastructureStack AtxUiStack --require-approval never -c existingVpcId=vpc-xxx -c existingSubnetIds=subnet-aaa,subnet-bbb -c existingSecurityGroupId=sg-ccc

# Subnets must be public (auto-assign public IP enabled) or private with a NAT gateway so Fargate tasks can reach Amazon ECR, Amazon S3, and Git repositories.

Step 4: Deploy Strands Agents to AgentCore runtime using AWS SAM

cd ../sam./deploy.sh

# Invoke the deploy Lambda to create the AgentCore Runtime via the bedrock-agentcore-control SDK (takes 2-5 minutes)

aws lambda invoke --function-name atx-deploy-agentcore \ --region us-east-1 \ --cli-binary-format raw-in-base64-out \ --payload '{"action":"deploy"}' \ --cli-read-timeout 900 /tmp/deploy-output.jsoncat /tmp/deploy-output.json

Step 5: Wire the AgentCore runtime ARN into the async invoke Lambda

ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)

RUNTIME_ARN=$(python3 -c "import json; print(json.loads(json.load(open('/tmp/deploy-output.json'))['body'])['runtime_arn'])")aws lambda update-function-configuration \ --function-name atx-async-invoke-agent \ --region us-east-1 \ --environment "Variables={AGENT_RUNTIME_ARN=${RUNTIME_ARN},RESULT_BUCKET=atx-custom-output-${ACCOUNT_ID},JOBS_TABLE=atx-transform-jobs}"

Step 6: Rebuild and deploy the frontend with AgentCore API endpoint

# Update the React application with the deployed API endpoint and redeploy it.

API_URL=$(aws cloudformation describe-stacks \ --stack-name AtxAgentCoreSAM \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \ --output text)

cd ../ui

VITE_API_ENDPOINT=$API_URL npx vite build./deploy-aws.sh

# This rebuilds the React application with the correct API endpoint, uploads it to Amazon S3, and invalidates the Amazon CloudFront distribution.

Step 7: Access the application

# After deployment completes, retrieve the CloudFront distribution URL from the AWS CloudFormation outputs and open it in your browser to access the application UI.

aws cloudformation describe-stacks \ --stack-name AtxUiStack \ --region us-east-1 \ --query 'Stacks[0].Outputs[?OutputKey==`WebsiteUrl`].OutputValue' \ --output text

Using the application

The UI exposes five tabs covering the complete modernization workflow: browsing available transformations, executing a transformation on a single repository, creating a new custom transformation with natural language, batch-processing a CSV of repositories, and tracking job status. This section walks through two of the most common flows.

Create a custom transformation from natural language

Open the Create Custom tab, describe the transformation in plain English (for example, “Upgrade Spring Boot 2 applications to Spring Boot 3”), and optionally provide a reference repository URL. The creation agent analyzes the source, generates a transformation definition, and publishes it to the ATX registry for reuse across the portfolio.

Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.

Figure 2: Describing a custom transformation in plain English. The form accepts a name, description, optional reference repository, and natural-language requirements.After submitting, the orchestrator clones the reference repository, analyzes the source, and generates a transformation definition tailored to the actual code patterns found in the codebase. This takes 1–5 minutes depending on repository size. The generated definition is then shown for review in the Jobs tab, where it can be edited before publishing to the ATX registry.

Figure 3: The AI-generated transformation definition shown for review in the Jobs tab. The agent analyzed the Flask codebase and produced a detailed definition covering routes, request handling, response patterns, and Blueprint architecture. The user can edit the definition in-place and click Publish to Registry when ready.Once published, the new transformation appears in the Transformations tab alongside AWS-managed transformations and can be executed the same way on any repository.

Run a batch of repositories from a CSV

Open the CSV Batch tab and upload a CSV listing repository URLs and target transformations. A sample `sample-batch.csv` is included in the repository at `agentic-atx-platform/ui/sample-batch.csv`. The preview shows the parsed rows before submission. On Submit All, each row becomes a separate AWS Batch job running in parallel, and the Jobs tab shows live status as repositories complete.

Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row.

Figure 4: Uploading a batch of repositories for parallel processing. The CSV lists a source repository URL, target transformation, optional validation commands, and additional plan context per row. Each row becomes an independent AWS Batch job on submission.

Clean up

To avoid recurring charges, remove the resources after trying the solution.

Step 1: Delete the SAM Stack

sam delete --stack-name AtxAgentCoreSAM --region us-east-1 --no-prompts

Step 2: Delete the CDK Stacks

Remove the three CDK stacks in reverse order. The S3 buckets are configured with `autoDeleteObjects: true`, so CDK will empty them before deletion.

cd cdk

npx cdk destroy AtxUiStack AtxInfrastructureStack AtxContainerStack --force

Conclusion

In this post, you learned how to build a generative AI–powered, agentic system for application modernization that can analyze application repositories, determine required code changes, create missing transformations, and execute those transformations at scale. By combining AWS Transform Custom for transformation execution with Amazon Bedrock AgentCore for orchestration, and Strands Agents for multi-agent coordination and AWS Transform container solution for parallel processing, this approach demonstrates how intelligent automation can be applied to large-scale code transformation workflows.

This solution directly addresses the challenges of traditional modernization approaches. It reduces manual effort by automating repository analysis and transformation mapping, eliminates gaps in transformation coverage by dynamically generating reusable transformations, and significantly improves scalability through parallel execution using AWS Batch.

By introducing a centralized, agent-driven workflow with built-in observability and state management, organizations can achieve faster, more consistent, and governed modernization across large application portfolios. To get started, deploy the solution in your AWS environment, test it with a sample repository or batch workload, and extend it by creating custom transformations tailored to your applications. You can further integrate this approach into your CI/CD pipelines to enable continuous modernization and accelerate your cloud migration initiatives.


About the authors

Kanishk Mahajan is Principal – AI/ML with AWS Professional Services. In this role, he leads GenAI and agentic transformations for some of AWS largest customers in Telco and Media & Entertaintment.

Sandeep Batchu is a Senior Security Architect at Amazon Web Services, with extensive experience in software engineering, solutions architecture, and cybersecurity. Passionate about bridging business outcomes with technological innovation, Sandeep guides customers through their cloud and generative AI journey, helping them design and implement secure, scalable, and resilient architectures in the era of AI-driven transformation.
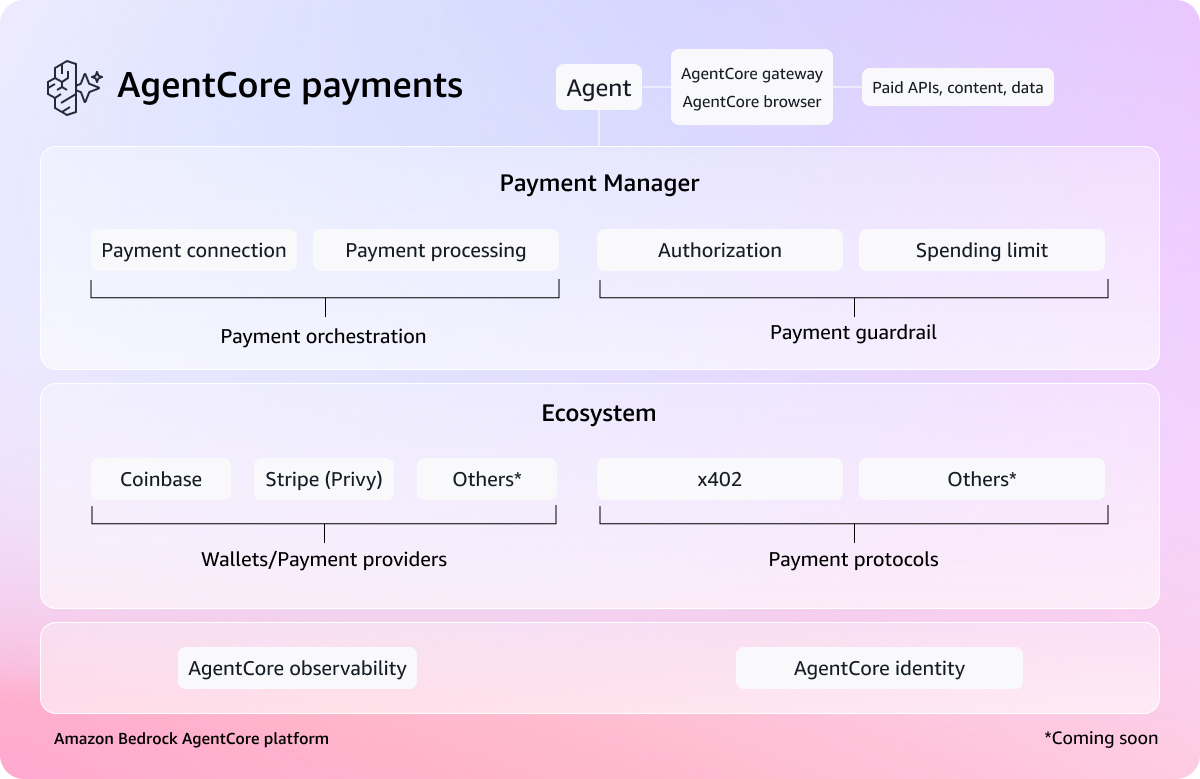
Venugopalan Vasudeven (Venu) is a Principal Specialist Solutions Architect at AWS, where he leads Agentic AI initiatives focused on AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

AWS Weekly Roundup: Amazon Bedrock AgentCore payments, Agent Toolkit for AWS, and more (May 11, 2026)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-agentcore-payments-agent-toolkit-for-aws-and-more-may-11-2026/

My most exciting news of last week: Amazon Bedrock AgentCore previewed the first managed payment capabilities enabling AI agents to autonomously access and pay for APIs, MCP servers, web content, and other agents. Built in partnership with Coinbase and Stripe, it removes the undifferentiated heavy lifting of building customized systems for billing, credential management, and compliance.

You can connect a Coinbase CDP wallet or Stripe Privy wallet as a payment connection, set session-level spending limits, and your agent transacts autonomously during execution. What excites me most is what AgentCore payments can unlock—like a research agent that can pay for real-time market data on the fly, or a coding agent calling paid APIs mid-task.

To learn more, visit the blog post, dive deeper using the documentation, and get started with the AgentCore CLI.

Last week’s launches
Here are last week’s launches that caught my attention:

  • Agent Toolkit for AWS – A production-ready suite of tools and guidance, available at no additional charge, that helps AI coding agents build on AWS with fewer errors, lower token costs, and enterprise-grade security controls. The Agent Toolkit for AWS is the successor to the MCP servers, plugins, and skills available on AWS Labs. To get started, visit the quick start guide or browse the available skills and plugins on GitHub.
  • AWS MCP Server GA – You can use a managed remote Model Context Protocol (MCP) server that gives AI agents and coding assistants secure, authenticated access to all AWS services through a small, fixed set of tools. It is part of the Agent Toolkit for AWS. To learn more, visit Seb Stormacq’s blog post.
  • Amazon WorkSpaces for AI agents (Preview) – You can use AI agents to securely access and operate desktop applications through managed WorkSpaces environments. This capability allows organizations to automate everyday workflows at scale while maintaining full enterprise-grade governance and compliance. To learn more, visit Micah Walter’s blog post.
  • Amazon EC2 M8idn/M8idb and R8idn/R8idb instances – These instances are powered by custom sixth-generation Intel Xeon Scalable processors available only on AWS and the latest sixth-generation AWS Nitro cards. These instances deliver up to 43% better compute performance per vCPU compared to previous-generation instances. M8idn/R8idn instances offer up to 600 Gbps network bandwidth, and M8idb/R8idb instances deliver up to 300 Gbps EBS bandwidth.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Additional updates
Here are some additional news items that you might find interesting:

  • Valkey turns two – Valkey stands as proof that open, community-driven technology innovates faster, scales further, and delivers more value than any single-vendor model. Valkey has surpassed 100 million Docker pulls (up 17x year over year) and attracted more than 225 contributors who have submitted over 1,500 pull requests, roughly double the development pace of Redis over the same period. You can also use the latest Valkey 9.0 in Amazon ElastiCache.
  • Query billion-scale vectors with SQL – You can learn how to query Amazon S3 Vectors from Amazon Aurora PostgreSQL-Compatible Edition using standard SQL, and how to combine vector similarity results with relational filters in a single query, for example, finding the most semantically similar products and then filtering by price, stock status, or tenant in one SQL statement.
  • Building an end-to-end agentic SRE using AWS DevOps Agent – Learn how to configure DevOps Agent Spaces that define an investigation scope, integrating seamlessly with Amazon CloudWatch, Splunk, GitHub, and Slack. You can also learn how to trigger automated investigations via webhooks, generate mitigation plans, and hand off agent-ready specs to coding agents like Kiro for implementation.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy