Tag Archives: AWS Big Data

Scheduling SQL queries on your Amazon Redshift data warehouse

Post Syndicated from Sain Das original https://aws.amazon.com/blogs/big-data/scheduling-sql-queries-on-your-amazon-redshift-data-warehouse/

Amazon Redshift is the most popular cloud data warehouse today, with tens of thousands of customers collectively processing over 2 exabytes of data on Amazon Redshift daily. Amazon Redshift is fully managed, scalable, secure, and integrates seamlessly with your data lake. In this post, we discuss how to set up and use the new query scheduling feature on Amazon Redshift.

Amazon Redshift users often need to run SQL queries or routine maintenance tasks at a regular schedule. You can now schedule statements directly from the Amazon Redshift console or by using the AWS Command Line Interface (AWS CLI) without having to use scripting and a scheduler like cron. You can schedule and run the SQL statement using Amazon EventBridge and the Amazon Redshift Data API. The results are available for 24 hours after running the SQL statement. This helps you in a variety of scenarios, such as when you need to do the following:

  • Run SQL queries during non-business hours
  • Load data using COPY statements every night
  • Unload data using UNLOAD nightly or at regular intervals throughout the day
  • Delete older data from tables as per regulatory or established data retention policies
  • Refresh materialized views manually at a regular frequency
  • Back up system tables every night

EventBridge is a serverless event bus service that makes it easy to connect your applications with data from a variety of sources. EventBridge delivers a stream of real-time data from your own applications, software as a service (SaaS) applications, and AWS services and routes that data to targets including Amazon Redshift clusters. Amazon Redshift integrates with EventBridge to allow you to schedule your SQL statements on recurring schedules and enables you to build event-driven applications. Beside scheduling SQL, you can also invoke the Amazon Redshift Data API in response to any other EventBridge event.

When creating a schedule using the Amazon Redshift console, you create an EventBridge rule with the specified schedule and attach a target (with the Amazon Redshift cluster information, login details, and SQL command run) to the rule. This rule then runs as per the schedule using EventBridge.

In this post, we describe how you can schedule SQL statements on Amazon Redshift using EventBridge, and also go over the required security privileges and the steps to schedule a SQL statement using both the AWS Management Console and the AWS CLI.

Prerequisites

To set this up, we need to make sure that the AWS Identity and Access Management (IAM) user (which we use to create the schedule and access the schedule history), the IAM role, and the AWS secret (which stores the database user name and password) are configured correctly.

  1. Make sure that the IAM user who is going to create the schedule has the AmazonEventBridgeFullAccess IAM policy attached to it. The IAM user should also have appropriate access to Amazon Redshift as per their role. We use the placeholder {USER_NAME} to refer to this IAM user in this post.
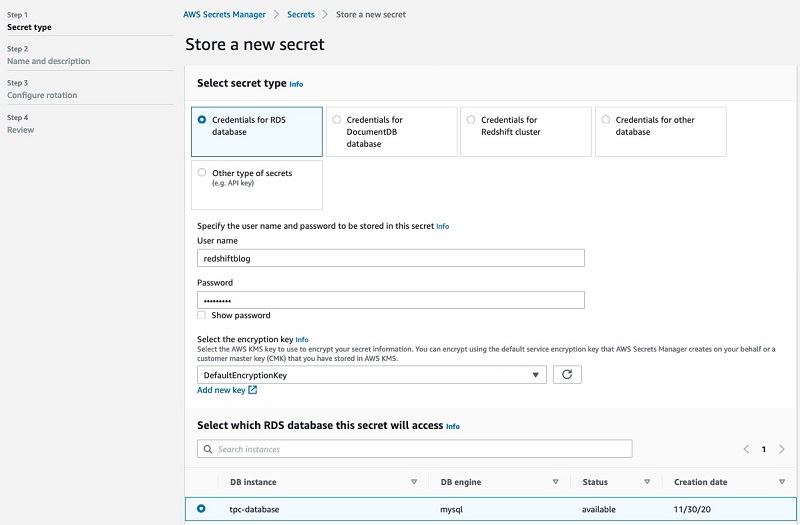
  1. Store the database credentials to be used for running the scheduled SQL statement securely using AWS Secrets Manager. If you already have a secret created, you can use that. If not, create a new secret to store the Amazon Redshift database name and user name.
  2. Create an IAM role for the Amazon Redshift service with the “Redshift Customizable” option and attach the AmazonRedshiftDataFullAccess AWS managed policy to it.
    1. Ensure that the role has the following trust relationships added to it:
      {
            "Sid": "S1",
            "Effect": "Allow",
            "Principal": {
              "Service": "events.amazonaws.com"
            },
            "Action": "sts:AssumeRole"
          }

    2. Add the following AssumeRole permissions so the user can see the schedule history list. Replace the {ACCOUNT_ID} with your AWS account ID and {USER_NAME} with the IAM user you set up:
      {
            "Sid": "S2",
            "Effect": "Allow",
            "Principal": {
              "AWS": "arn:aws:iam::{ACCOUNT_ID}:user/{USER_NAME}"
            },
            "Action": "sts:AssumeRole"
      }

    We use the placeholder {ROLE_NAME} to refer to this role in this post.

  1. In addition to the preceding AssumeRole permissions, the IAM user has to be granted AssumeRole permissions on the IAM role you created in order to view the schedule history:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "S3",
                "Effect": "Allow",
                "Action": "sts:AssumeRole",
                "Resource": "arn:aws:iam::{ACCOUNT_ID}:role/{ROLE_NAME}"
            }
        ]
    }

Now that we have completed the security setup required to schedule SQL statements and view their history, let’s schedule a SQL statement to run at a regular frequency. We can do this using the console or the AWS CLI. We discuss both approaches in this post.

Scheduling the SQL statement using the console

Let’s take the example of a fairly common use case where data from a table has to be extracted daily (or at another regular frequency) into Amazon Simple Storage Service (Amazon S3) for analysis by data scientists or data analysts. You can accomplish this by scheduling an UNLOAD command to run daily to export data from the table to the data lake on Amazon S3. See the following code:

unload ('select * from edw.trxns')
to 's3://mybucket/'
iam_role 'arn:aws:iam::{ACCOUNT_ID}:role/{ROLE_NAME_2}'
PARQUET
PARTITION BY (trxn_dt);
;

{ROLE_NAME_2} in the preceding code is not the same as {ROLE_NAME}. {ROLE_NAME_2} should be an IAM role that has permissions to run the UNLOAD command successfully.

We can schedule this UNLOAD statement to run every day at 4:00 AM UTC using the following steps:

  1. Sign in to the console. Make sure the IAM user has been granted the necessary permissions.
  2. On the Amazon Redshift console, open the query editor.
  3. Choose Schedule.

Choose Schedule.

  1. In the Scheduler permissions section, for IAM role, choose the role you created earlier.

If you don’t have IAM read permissions, you may not see the IAM role in the drop-down menu. In that case, you can enter the Amazon Resource Name (ARN) of the IAM role that you created.

  1. For Authentication, select AWS Secrets Manager.
  2. For Secret, choose the secret you configured earlier, which contains the database user name and password.

You can also use Temporary credentials for authentication as explained in the AWS documentation.

  1. For Database name, enter a name.

For Database name, enter a name.

  1. In the Query Information section, for Scheduled query name, enter a name for the query.
  2. For SQL query, enter the SQL code.

You also have the ability to upload a SQL query from a file.

You also have the ability to upload a SQL query from a file.

  1. In the Scheduling options section, for Schedule query by, select Run frequency.
  2. For Repeat by, choose Day.
  3. For Repeat every, enter 1.
  4. For Repeat at time (UTC), enter 04:00.

For Repeat at time (UTC), enter 04:00.

  1. In the Monitoring section, you can choose to enable notifications via email or text using Amazon Simple Notification Service (Amazon SNS).

If you decide to enable notifications, make sure that the Publish action has been granted to events.amazonaws.com on the SNS topic. You can do this by adding the following snippet to the access policy of the SNS topic. Replace ACCOUNT_ID and SNS_TOPIC_NAME with appropriate values. If you choose to create a new SNS topic during the schedule creation process, then the following access is granted automatically.

{
      "Sid": "Allow_Publish_Events",
      "Effect": "Allow",
      "Principal": {
        "Service": "events.amazonaws.com"
      },
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:us-east-1:{ACCOUNT_ID}:{SNS_TOPIC_NAME}"
  }

Scheduling the SQL statement using the AWS CLI

You can also schedule SQL statements via the AWS CLI using EventBridge and the Amazon Redshift Data API. For more information about the Amazon Redshift Data API, see Using the Amazon Redshift Data API to interact with Amazon Redshift clusters.

In the following example, we set up a schedule to refresh a materialized view (called mv_cust_trans_hist) on Amazon Redshift daily at 2:00 AM UTC.

  1. Create an event rule. The following command creates a rule named scheduled-refresh-mv-cust-trans-hist and schedules it to run daily at 2:00 AM UTC. The schedule expression can be provided using cron or rate expressions.
    aws events put-rule \
    --name scheduled-refresh-mv-cust-trans-hist \
    --schedule-expression "cron(0 22 * * ? *)"

  1. Create a JSON object that contains the Amazon Redshift Data API parameters:
    1. For ARN, enter the ARN of your Amazon Redshift cluster.
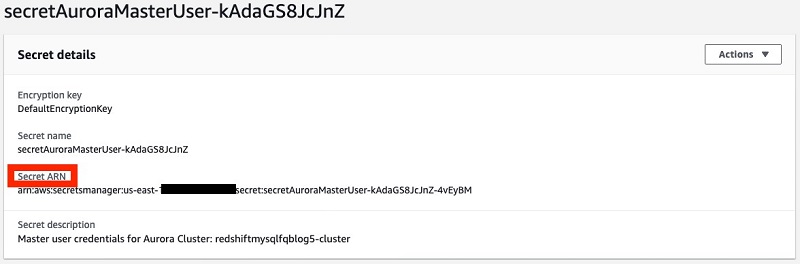
    2. For the RoleArn and the SecretManagerArn fields, use the ARNs for the role and secret you created earlier.
    3. Enter the database name and the SQL statement to be scheduled for the database and SQL fields.
    4. You can enter any name for the StatementName field.
    5. If you want an event to be sent after the SQL statement has been run, you can set the WithEvent parameter to true. You can then use that event to trigger other SQL statements if needed.
      {
      "Rule": "scheduled-refresh-mv-cust-trans-hist",
      "EventBusName": "default",
      "Targets": 
      [
      {
      "Id": "scheduled-refresh-mv-cust-trans-hist",
      "Arn": "arn:aws:redshift:us-east-1:{ACCOUNT_ID}:cluster:{REDSHIFT_CLUSTER_IDENTIFIER}",
      "RoleArn": "arn:aws:iam::{ACCOUNT_ID}:role/{ROLE_NAME}",
      "RedshiftDataParameters": 
      {
      "SecretManagerArn": "arn:aws:secretsmanager:us-east-1:{ACCOUNT_ID}:secret:{SECRET_NAME-xxxxxx}",
      "Database": "dev",
      "Sql": "REFRESH MATERIALIZED VIEW mv_cust_trans_hist;",
      "StatementName": "refresh-mv-cust-trans-hist",
      "WithEvent": true
      }
      }
      ]
      }

  1. Create an event target using the JSON file created in the previous step:
    aws events put-targets --cli-input-json file://data.json

Additional commands

We have now set up the schedule to refresh the materialized view using the AWS CLI. Let’s quickly go over a few more CLI commands that are useful while scheduling tasks:

  • To list all targets for a particular rule, use:
    aws events list-targets-by-rule --rule <rule-name> 

  • To list all rules, use:
    aws events list-rules

  • To remove a target from a specific rule, use:
    aws events remove-targets --rule <rule-name> --ids 2 

  • To delete a rule, use:
    aws events delete-rule --name <rule-name>

  • To view the schedule history for a particular scheduled SQL statement, use:
    aws redshift-data list-statements --status ALL --statement-name <statement-name>

Retrieving the SQL status and results

After the schedule is set up, scheduled queries might be listed in the following places:

  • On the Schedules tab of the details page of your cluster.
  • On the scheduled queries list that you can reach from the navigation pane. To see the list, in the navigation pane, choose Queries and Schedule query list.
  • On the Scheduled queries tab of the query editor (see the following screenshot).

On the Scheduled queries tab of the query editor (see the following screenshot).

  1. Choose the schedule name to see more details about the scheduled query, including details about any previous runs of the schedule.
  2. In the Schedule history section, you can see the ID (which can be used to retrieve SQL statement results), start time, end time, status, and elapsed time for each previous run of the scheduled SQL statement.

In the Schedule history section, you can see the ID.

To retrieve the SQL results, you need to use the AWS CLI (or AWS SDK), but you have to assume the role you created earlier.

  1. To assume this role, run the following command on the command line using the IAM user you configured.
    aws sts assume-role --role-arn "arn:aws:iam::{Account_ID}:role/{Role_Name}" --role-session-name AWSCLI-Session

The command returns a result set similar to the following code:

{
    "Credentials": {
        "AccessKeyId": "XXXXXXXXXXXX",
        "SecretAccessKey": "XXXXXXXXXXXXXXXXX",
        "SessionToken": "xxxxxxxxxxxxxxxxxxxxx”
        "Expiration": "2020-10-09T17:13:23+00:00"
    },
    "AssumedRoleUser": {
        "AssumedRoleId": "XXXXXXXXXXXXXXXXX:AWSCLI-Session",
        "Arn": "arn:aws:sts::{Account_ID}:assumed-role/{Role_Name}/AWSCLI-Session"
    }
}
  1. Create three environment variables to assume the IAM role by running the following commands. Use the access key, secret access key, and the session token from the preceding results.
    export AWS_ACCESS_KEY_ID=RoleAccessKeyID
    export AWS_SECRET_ACCESS_KEY=RoleSecretKey
    export AWS_SESSION_TOKEN=RoleSessionToken

  1. Run the following command to retrieve the results of the SQL statement. Replace the ID with the ID from the schedule history on the console.
    aws redshift-data get-statement-result --id xxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx --region us-east-1 

Conclusion

The ability to schedule SQL statements using the Amazon Redshift Data API and EventBridge simplifies running routine tasks that previously required scripting. You can configure schedules and manage them either via the console or the AWS CLI. You can also see the previous runs of any scheduled SQL statements directly from the console and choose to be notified when it runs.


About the Authors

Sain Das is an Analytics Specialist Solutions Architect at AWS and helps customers build scalable cloud solutions that help turn data into actionable insights.


Vijetha Parampally Vijayakumar is a full stack software development engineer with Amazon Redshift. She is specialized in building applications for Big data, Databases and Analytics.


André Dias is a Systems Development Engineer working in the Amazon Redshift team. André’s passionate about learning and building new AWS Services and has worked in the Redshift Data API. He specializes in building highly available and cost-effective infrastructure using AWS.

Dream11’s journey to building their Data Highway on AWS

Post Syndicated from Pradip Thoke original https://aws.amazon.com/blogs/big-data/dream11s-journey-to-building-their-data-highway-on-aws/

This is a guest post co-authored by Pradip Thoke of Dream11. In their own words, “Dream11, the flagship brand of Dream Sports, is India’s biggest fantasy sports platform, with more than 100 million users. We have infused the latest technologies of analytics, machine learning, social networks, and media technologies to enhance our users’ experience. Dream11 is the epitome of the Indian sports technology revolution.”

Since inception, Dream11 has been a data-driven sports technology brand. 

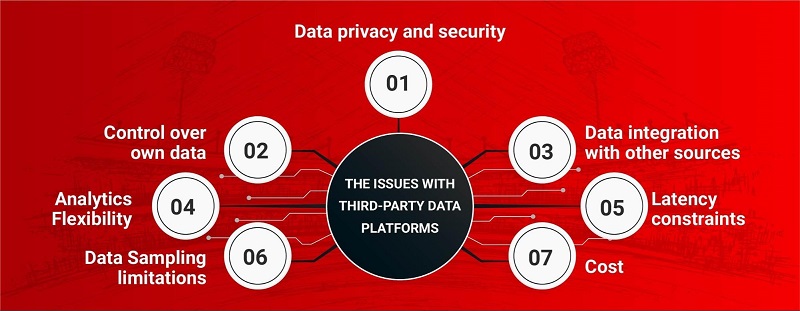
Since inception, Dream11 has been a data-driven sports technology brand. The systems that power Dream11, including their transactional data warehouse, run on AWS. As Dream11 hosts fantasy sports contests that are joined by millions of Indian sports fans, they have large volumes of transactional data that is organized in a well-defined Amazon Redshift data warehouse. Previously they were using 3rd party services to collect, analyze and build models over user interaction data combined with transactional data. Although this approach was convenient, it presented certain critical issues:

  • The approach wasn’t conducive to 360-degree user analytics. Dream11’s user interactions data wasn’t present on the cloud, where the rest of Dream11’s infrastructure and data were present (AWS, in this case). To get a complete picture of a user’s experience and journey, the user’s interaction data (client events) needs to be analyzed alongside their transactional data (server events). This is known as 360-degree user analytics.
  • It wasn’t possible to get accurate user journey funnel reports. Currently, there are limitations with every tool available on the market with respect to identifying and mapping a given user’s actions across multiple platforms (on the web, iOS, or Android), as well as multiple related apps. This use case is specifically important if your company is a parent to other companies.
  • The statistics on user behavior that Dream11 was getting weren’t as accurate as they wanted. Some of the popular services they were using for web & mobile analytics use the technique of sampling to be able to deal with high volumes of data. Although this is a well-regarded technique to deal with high volumes of data and provides reasonable accuracy in multiple cases, Dream11 wanted statistics to be as accurate as possible.
  • The analytics wasn’t real-time. Dream11 experiences intense use by their users just before and during the real-life sports matches, so real-time and near-real-time analytics is very critical for them. This need wasn’t sufficiently met by the plethora of services they were using.
  • Their approach was leading to high cost for custom analytics for Dream11’s user interactions data, consisting of hundreds of event types. Serverless query engines typically charge by the amount of data scanned and so it can get very expensive if events data isn’t organized properly in separate tables in a data lake to enable selective access.

All these concerns and needs, led Dream11 to conclude that they needed their own centralized 360-degree analytics platform.

All these concerns and needs, led Dream11 to conclude that they needed their own centralized 360-degree analytics platform. Therefore, they embarked on the Data Highway project on AWS.

This project has additional advantages. It is increasingly becoming important to store and process data securely. Having everything in-house can help Dream11 with data security and data privacy objectives. The platform enables 360-degree customer analytics, which further allows Dream11 to do intelligent user segmentation in-house and share only those segments (without exposing underlying transactional or interactions data) with third-party messaging service providers. 

Design goals

Dream11 had the following design goals for the project:

  • The system should be easy to maintain and should be able to handle a very high volume of data, consisting of billions of events and terabytes of data daily.
  • The cost should be low and should be pay-as-you-go.
  • Dream11’s web and mobile developers regularly create new types of events to capture new types of interactions. Whenever they add new types of events, they should be immediately available in the system for analytics, and their statistics should immediately reflect in relevant dashboards and reports without any human intervention.
  • Certain types of statistics (such as concurrency) should be available in real-time and near-real time—within 5 minutes or less.
  • Dream11 should be able to use custom logic to calculate key statistics. The analytics should be accurate—no more sampling.
  • The data for various events should be neatly organized in separate tables and analytics-friendly file formats.
  • Although Dream11 will have a common data lake, they shouldn’t be constrained to use a single analytics engine for all types of analytics. Different types of analytics engines excel for different types of queries.
  • The Product Management team should have access to views they commonly use in their decision-making process, such as funnels and user flow diagrams.
  • The system should be extensible by adding lanes in the system. Lanes allow you to reuse your basic setup without mixing events data for different business units. It also potentially allows you to study user behavior across different apps.
  • The system should be able to build 360-degree user profiles
  • The system should provide alerting on important changes to key business metrics.
  • Last but not the least, the system should be secure and reliable with 6 nines of availability guarantee.

Data Highway architecture

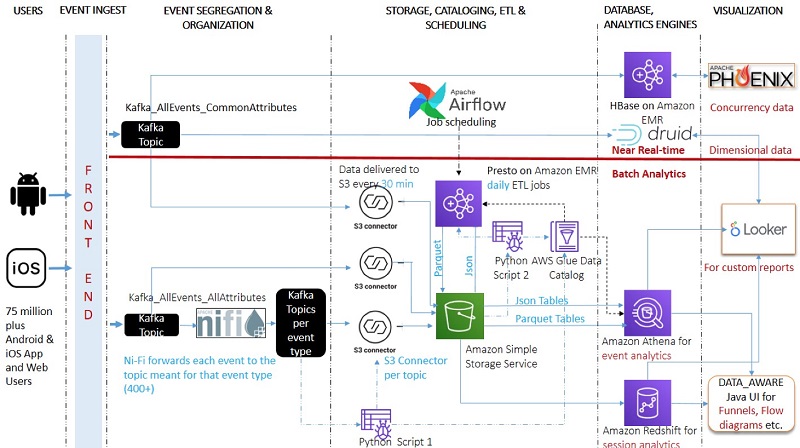
In less than 3 months, Dream11’s data team built a system that met all the aforementioned goals. The following diagram shows the high-level architecture.

The following diagram shows the high-level architecture.

For this project, they used the following components:

The rest of this post explains the various design choices and trade-offs made by the Dream11’s data engineers. 

Event ingestion, segregation, and organization

Dream11 has several hundred event types. These events have common attributes and specific attributes. The following diagram shows the logical structure of these events.

The following diagram shows the logical structure of these events.

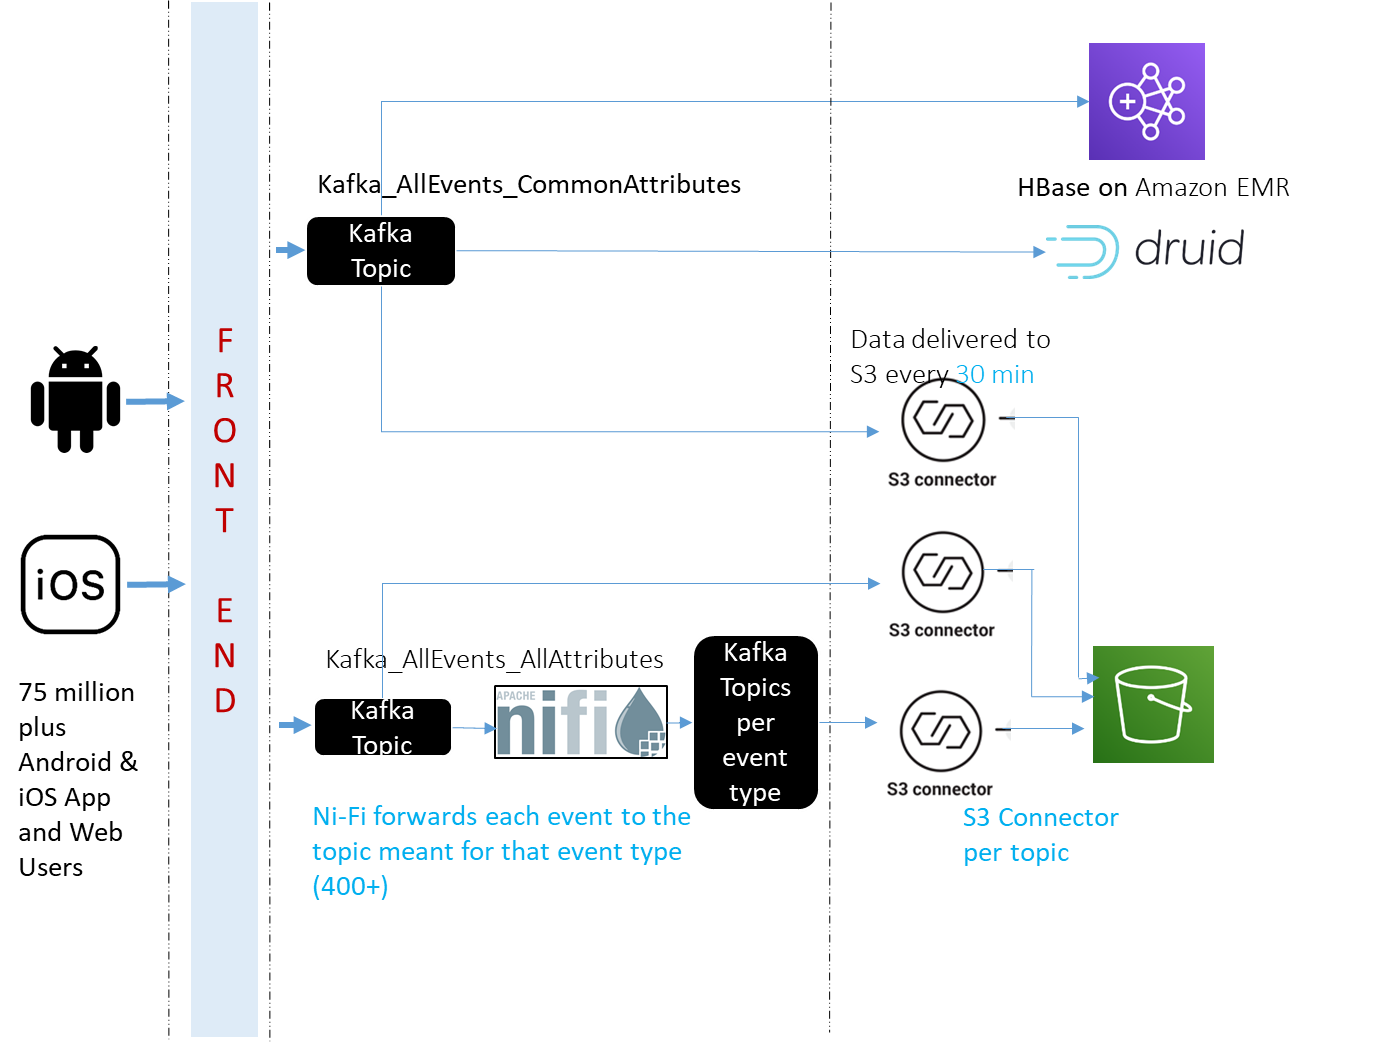
When the front end receives an event, it saves fields up to common attributes into a message and posts it to Kafka_AllEvents_CommonAttributes. This Kafka topic is the source for the following systems:

  • Apache HBase on Amazon EMR – Provides real-time concurrency analytics
  • Apache Druid – Provides near real-time dimensional analytics
  • Amazon Redshift – Provides session analytics

The front end also saves events, as they are, into Kafka_AllEvents_AllAttributes. These events are further picked by Apache Ni-Fi, which forwards them to their respective topics. Apache Ni-Fi supports data routing, transformation, and system mediation logic using powerful and scalable directed graphs. Data is transformed and published to Kafka by using a combination of RouteOnAttribute and JoltTransformJSON processors (to parse JSON). Apache Ni-Fi basically reads event names and posts to the Kafka topic with matching names. If Kafka doesn’t have a topic with that name, it creates a new topic with that name. You can configure your Kafka brokers to auto-create a topic when a message is received for a non-existent topic.

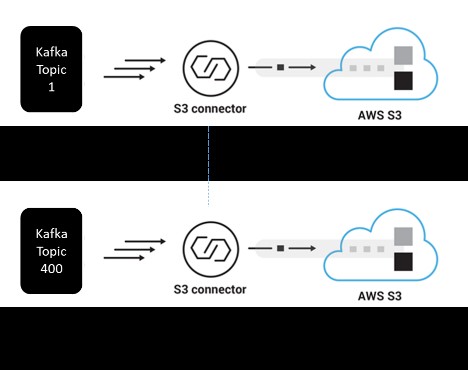
The following diagram illustrates the Amazon S3 sink connector per Kafka topic.

  The following diagram illustrates the Amazon S3 sink connector per Kafka topic.

The following diagram summarizes the overall design of the system for event ingestion, segregation, and organization.


The following diagram summarizes the overall design of the system for event ingestion, segregation, and organization.

Storage, cataloging, ETL, and scheduling

In this section, we discuss how Dream11 updates their AWS Glue Data Catalog, performs extract, transform, and load (ETL) jobs with Amazon EMR Presto, and uses Apache Airflow for schedule management.

Updating the AWS Glue Data Catalog with metadata for the target table

The AWS Glue Data Catalog provides a unified metadata repository across a variety of data sources and data formats. It provides out-of-the-box integration with Amazon S3, Amazon Relational Database Service (Amazon RDS), Amazon Redshift, Amazon Redshift Spectrum, Athena, Amazon EMR, and any application compatible with the Apache Hive metastore. You can create your table definitions one time and query across engines. For more information, see FAQ: Upgrading to the AWS Glue Data Catalog.

Because this Data Catalog is accessible from multiple services that were going to be used for the Data Highway project, Dream11 decided to use it to register all the table definitions.

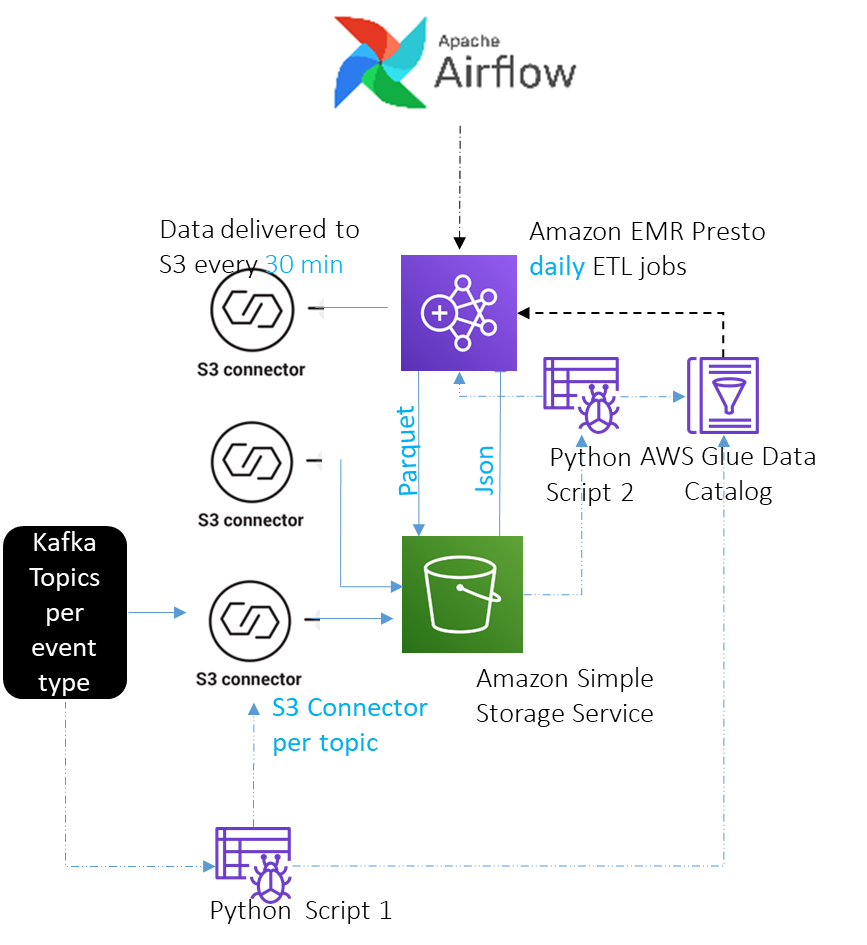
Registering tables with AWS Glue Data Catalog is easy. You can use an AWS Glue crawler. It can infer schema from files in Amazon S3 and register a table in the Data Catalog. It works quite well, but Dream11 needed additional actions, such as automatically configuring Kafka Amazon S3 sink connectors etc. Therefore, they developed two Python based crawlers.

The first Python based crawler runs every 2 hours and looks up Kafka topics. If it finds a new topic, it configures a Kafka Amazon S3 connector sink to dump its data to Amazon S3 every 30 minutes in JSON Gzip format. It also registers a table with Glue Data Catalog so that users can query the JSON data directly, if needed. 

The second Python based crawler runs once a day and registers a corresponding table for each new table created that day to hold flattened data (Parquet, Snappy). It infers schemas and registers tables with the Data Catalog using its Table API. It adds customization needed by the Dream11 team to the metadata. It then creates Amazon EMR Presto ETL jobs to convert JSON, Gzip data to Parquet, Snappy, and registers them with Apache Airflow to run every 24 hours.

ETL with Amazon EMR Presto

Dream11 has a multi node, long-running, multi-purpose EMR cluster. They decided to run scheduled ETL jobs on it for the Data Highway project.

ETL for an event table involves a simple SELECT FROM -> INSERT INTO command to convert JSON (Gzip) to Parquet (Snappy). Converted data takes up to 70% less space, results in 10 times improvement in Athena query performance. ETL happens once a day. Tables are partitioned by day.

Data received on Kafka_AllEvents_CommonAttributes topic is loaded to Redshift. ETL involves SELECT FROM -> INSERT INTO to convert JSON (Gzip) to CSV, followed by Amazon Redshift COPY.

Apache Airflow for schedule management

Apache Airflow is an open-source tool for authoring and orchestrating big data workflows. With Apache Airflow, data engineers define direct acyclic graphs (DAGs). DAGs describe how to run a workflow and are written in Python. Workflows are designed as a DAG that groups tasks that run independently. The DAG keeps track of the relationships and dependencies between tasks.

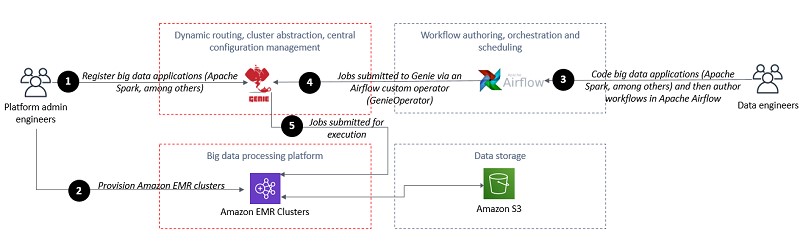
Dream11 uses Apache Airflow to schedule Python scripts and over few hundred ETL jobs on Amazon EMR Presto to convert JSON (Gzip) data for over few hundred events to Parquet (Snappy) format, and converts JSON data containing common attributes for all events to CSV before loading to Amazon Redshift. For more information, see Orchestrate big data workflows with Apache Airflow, Genie, and Amazon EMR: Part 1.

The following diagram shows the workflow to connect Apache Airflow to Amazon EMR.

The following diagram shows the workflow to connect Apache Airflow to Amazon EMR.

The following diagram summarizes the overall design of the system for storage, cataloging, ETL, and scheduling.

The following diagram summarizes the overall design of the system for storage, cataloging, ETL, and scheduling. 

Real-time and near-real-time analytics

In this section, we discuss the real-time and near-real-time analytics performed on Dream11’s data.

Concurrency analytics with Apache Druid

Apache Druid is an OLAP-style data store. It computes facts and metrics against various dimensions while data is being loaded. This avoids the need to compute results when a query is run.

Dream11’s web and mobile events are loaded from the Kafka_AllEvents_CommonAttributes topic to Apache Druid with the help of the Apache Druid Kafka indexing service. Dream11 has a dashboard with different granularity levels and dimensions such as app version, org, and other dimensions present in the common event attributes list.

Finding active users with Amazon EMR HBase

Dream11 also needs to identify individual active users at any given time or during a given window. This is required by other downstream teams such as the Data Science team and Digital User Engagement team.

With the help of a Java consumer, they push all events from the Kafka_AllEvents_ CommonAttributes topic to HBase on an EMR cluster with just required user dimensions. They can query the data in HBase with SQL syntax supported by the Apache Phoenix interface. 

Session analytics with Amazon Redshift

Dream11 maintains their transactional data warehouse on Amazon Redshift multi node cluster. Amazon Redshift allows them to run complex SQL queries efficiently. Amazon Redshift would have been a natural choice for event analytics for hundreds of event types. However, in Dream11’s case, events data grows very rapidly and this would be a lot of data in Amazon Redshift. Also, this data loses its value rapidly as time passes (relatively speaking) compared with transactional data. Therefore, they decided to do only session analytics in Amazon Redshift to benefit from its complex SQL query capabilities and to do analytics for individual events with the help of Athena (which we discuss in the next section).

Data received on Kafka_AllEvents_CommonAttributes is loaded into Amazon S3 every 30 minutes by the associated kafka connector sink. This data is in JSON format with Gzip compression. Every 24 hours, a job runs on Amazon EMR Presto that flattens this data into CSV format. The data is loaded into Amazon Redshift with the COPY command. The data gets loaded first into a staging table. Data in the staging table is aggregated to get sessions data. Amazon Redshift already has transactional data from other tables that, combined now with the session data, allows Dream11 to perform 360-degree user analytics. They can now easily segment users based on their interactions data and transactions data. They can then run campaigns for those users with the help of messaging platforms. 

Event analytics with Athena

Dream11 uses Athena to analyze the data in Amazon S3. Athena is an interactive query service that makes it easy to analyze data in Amazon S3 using standard SQL. Athena is serverless, so there is no infrastructure to manage, and you pay only for the queries that you run. It made perfect sense to organize data for over hundreds of event tables in Amazon S3 and analyze them with Athena on demand.

With Athena, you’re charged based on the amount of data scanned by each query. You can get significant cost savings and performance gains by compressing, partitioning, or converting your data to a columnar format, because each of those operations reduces the amount of data that Athena needs to scan to run a query. For more information, see Top 10 Performance Tuning Tips for Amazon Athena.

As discussed before, Dream11 has registered over hundreds of tables for events data in JSON format, and similar number of tables for events data in Parquet format with the AWS Glue Data Catalog. They observed a performance gain of 10 times on conversion of data format to Parquet, and an 80% savings in space. Data in Amazon S3 can be queried directly through the Athena UI with SQL queries. The other option they use is connecting to Athena using a JDBC driver from Looker and their custom Java UI for the Data Aware project.

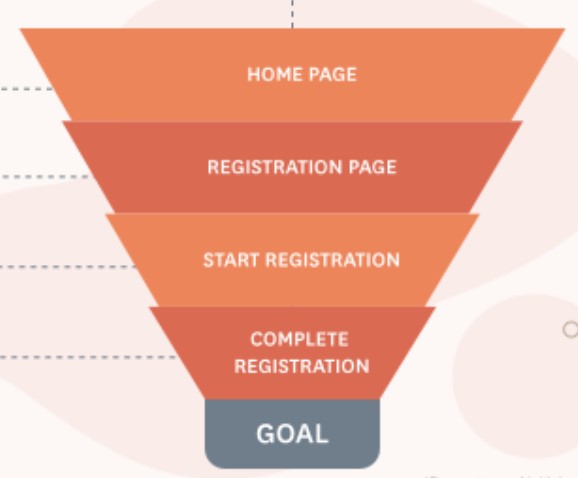
Athena helps Dream11 produce funnel analytics and user path analytics reports and visualizations.

  Athena helps Dream11 produce funnel analytics and user path analytics reports and visualizations.

 The following diagram summarizes the overall design of the system for real-time and near-real-time analytics and visualization.

 The following diagram summarizes the overall design of the system for real-time and near-real-time analytics and visualization.


Conclusion

This architecture has enabled Dream11 to achieve all the design goals they set out with. Results of analytics for real-time requirements are available under millisecond latency, and the system costs 40% less than the previous system. Analytics is performed with all the data without sampling, so results are accurate and reliable. All the data and analytics engines are within Dream11’s AWS account, improving data security and privacy.

As of this writing, the system handles 14 TB of data per day and it has served 80 million requests per minute at peak during Dream11 IPL 2020.

Doing all their analytics in-house on AWS has not just improved speed, accuracy, and data security, it has also enabled newer possibilities. Now Dream11 has a 360-degree view of their users. They can study their users’ progress across multiple platforms – web, Android, and IOS. This new system is enabling novel applications of machine learning, digital user engagement, and social media technologies at Dream11.


About the Authors

Pradip Thoke is a AVP Data Engineering at Dream11 and leads their Data Engineering team. The team involved in this implementation includes Vikas Gite, Salman Dhariwala, Naincy Suman, Lavanya Pulijala, Ruturaj Bhokre, Dhanraj Gaikwad, Vishal Verma, Hitesh Bansal, Sandesh Shingare, Renu Yadav, Yash Anand, Akshay Rochwani, Alokh P, Sunaim and Nandeesh Bijoor.


Girish Patil is a Principal Architect AI, Big Data, India Scale Apps for Amazon.

Building high-quality benchmark tests for Amazon Redshift using Apache JMeter

Post Syndicated from Asser Moustafa original https://aws.amazon.com/blogs/big-data/building-high-quality-benchmark-tests-for-amazon-redshift-using-apache-jmeter/

In the introductory post of this series, we discussed benchmarking benefits and best practices common across different open-source benchmarking tools. As a reminder of why benchmarking is important, Amazon Redshift allows you to scale storage and compute independently, and for you to choose an appropriately balanced compute layer, you need to profile the compute requirements of various production workloads. Existing Amazon Redshift customers also desire an approach to scale up with eyes wide open, and benchmarking different Amazon Redshift cluster configurations against various production workloads can help you appropriately accommodate workload expansion. In addition, you may also use benchmark tests to proactively monitor a production cluster’s performance in real time.

For prospective Amazon Redshift customers, benchmarking Amazon Redshift is often one of the main components of evaluation and a key source of insight into the price-to-performance ratio of different Amazon Redshift configurations.

Open-source tools, with their cost-efficiency and vendor neutrality, are often the preferred choice for profiling your production workloads and benchmark tests. However, best practices for using these tools are scarce, possibly resulting in flawed compute profiles, flawed benchmark results, customer frustration, or bloated timelines.

As mentioned, this series is divided into multiple installments, with the first installment discussing general best practices for benchmarking, and the subsequent installments discussing the strengths and challenges with different open-source tools such as SQLWorkbench, psql, and Apache JMeter. In this post, we discuss benchmarking Amazon Redshift with the Apache JMeter open-source tool.

One final point before we get started: there is a lot that could be said about benchmarking—more than can be accommodated in a single post. Analytics Specialists Solutions Architects such as myself frequently and happily engage with current and prospective customers to help you evaluate your benchmarking strategy and approach at no charge. I highly recommend you take advantage of that benefit by reaching out to your AWS account SA.

Apache JMeter

Apache JMeter is an open-source load testing application written in Java that you can use to load test web applications, backend server applications, databases, and more. You can run it on Windows and a number of different Linux/UNIX systems; for this post we run it in a Windows environment. To install Apache JMeter on a Windows EC2 machine, complete the following steps:

  1. Launch a Windows EC2 instance using a Windows Server AMI (such as Microsoft Windows Server 2019 Base).
  2. Connect via RDP to the Windows EC2 Instance (RDP for macOS can be downloaded from Apple’s App Store).
  3. Download and unzip the Apache JMeter .zip file from the Apache JMeter download page.
  4. Download the Redshift JDBC driver and add the driver .jar file to JMeter’s /lib When setting up the JDBC connection in the JMeter GUI, use com.amazon.redshift.jdbc.Driver as the driver class name).
  5. Download the Apache Plugins Manager .jar file to JMeter’s /lib/ext The Apache Plugins Manager enables additional crucial functionality in Apache JMeter for benchmark testing (such as Ultimate Thread Group).
  6. Increase the JVM heap size for Apache JMeter by changing the corresponding JVM parameters in the jmeter.bat file located in the Apache JMeter /bin folder. For example, see the following code:
    edit C:\Dev\apache-jmeter-5.1.1\bin\jmeter.bat rem set HEAP=-Xms1g -Xmx1g -XX:MaxMetaspaceSize=256m set HEAP=-Xms5g -Xmx5g -XX:MaxMetaspaceSize=1g

  1. Choose the jmeter.bat file (double-click) to start Apache JMeter.

Apache JMeter supports both GUI and CLI modes, and although you may find the Apache JMeter GUI straightforward with a relatively small learning curve, it’s highly recommended that you use the Apache JMeter GUI primarily for defining benchmark tests, and perhaps running small-to-medium-sized benchmark tests. For large load tests, it’s highly recommended that you use the Apache JMeter CLI to minimize the risk of the Apache JMeter GUI exhausting its host’s compute resources, causing it to enter a non-responsive state or fail with an out-of-memory error. Using the CLI for large load tests also helps minimize any impact on the benchmark results.

In the following example, I demonstrate creating a straightforward load test using both the Apache JMeter GUI and CLI. The load test aims to measure query throughput while simulating 50 concurrent users with the following personas:

  • 20 users submit only small queries, which are of low complexity and typically have a runtime of 0–30 seconds in the current system, such as business intelligence analyst queries
  • 20 users submit only medium queries, which are of moderate complexity and typically have a runtime of 31–300 seconds in the current system, such as data engineer queries
  • 10 users submit only large queries, which are very complex and typically have a runtime over 5 minutes in the current system, such as data scientist queries

The load test is configured to run for 15 minutes, which is a pretty short test duration, so you can increase that setting to 30 minutes or more. We rely on JMeter’s query throughput calculation, but we can also manually compute query throughput from the runtime metadata that is gathered if we so desire.

For this post, I skip over discussing the possible Amazon Redshift cluster tweaks that you could use to squeeze every drop of performance out of Amazon Redshift, and instead rely on the strength of its default state to be optimized to achieve excellent query throughput on diverse workloads.

Apache JMeter has a number of building blocks, such as thread groups, that can be used to define a wide variety of benchmark tests, and each building block can have a number of community implementations (for example, Arrivals Thread Group or Ultimate Thread Group).

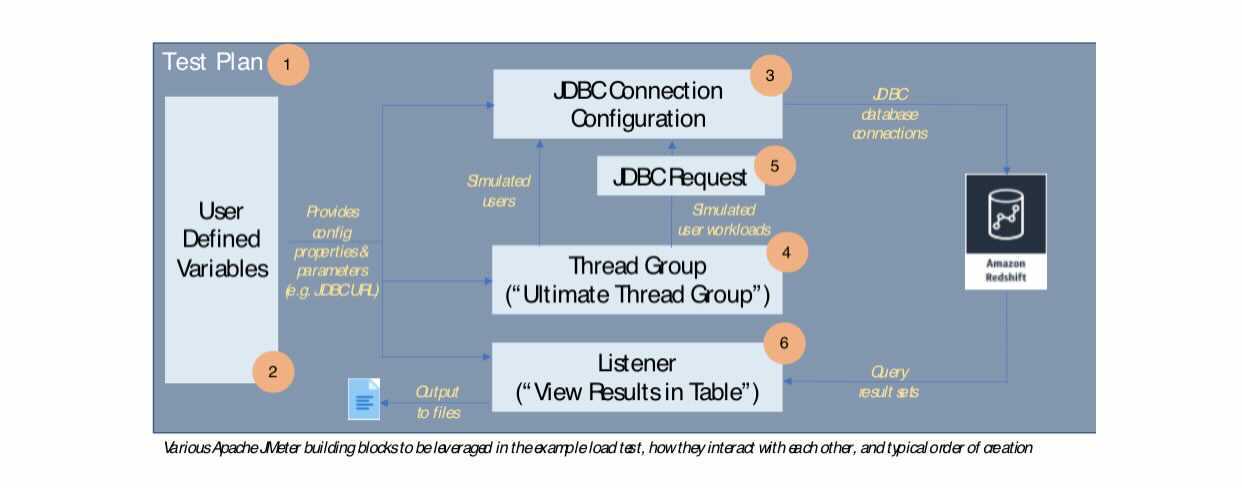
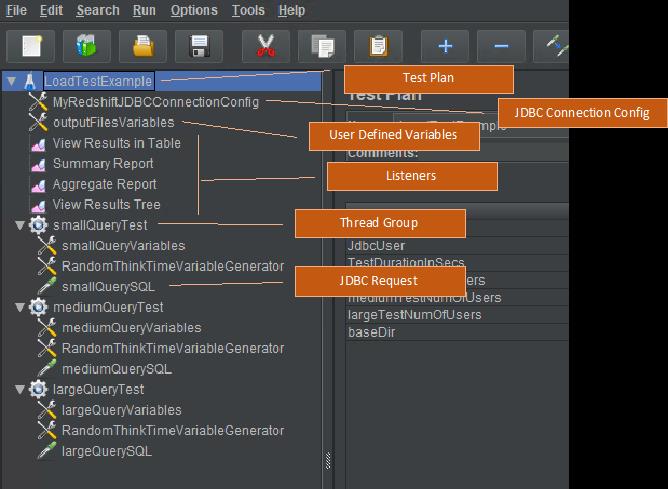
The following diagram provides a basic illustration of the various Apache JMeter building blocks to be leveraged in this load test, how they interact with each other, and the typical order in which are they created; in some cases, I mention the specific implementation of the building block to be used in parenthesis (such as Ultimate Thread Group).

The following table delves deeper into the purpose that each building block serves in our load test.

Apache JMeter Component Purpose
Test Plan Represents an atomic test case (simulate 50 users concurrently querying a Redshift cluster with twice the baseline node count)
JDBC Connection Configuration Represents all the JDBC information needed to connect to the Amazon Redshift cluster (such as JDBC URL, username, and password)
User Defined Variables A collection of key-value pairs that can be used as parameters throughout the test plan and make it easier to maintain or change the test behavior
Listener Captures and displays or writes test output such as SQL result sets
Thread Group A simulated group of users that perform the test function (submit a SQL query)
JDBC Request The action to be taken by the simulated users (SQL query text)

Apache JMeter (GUI)

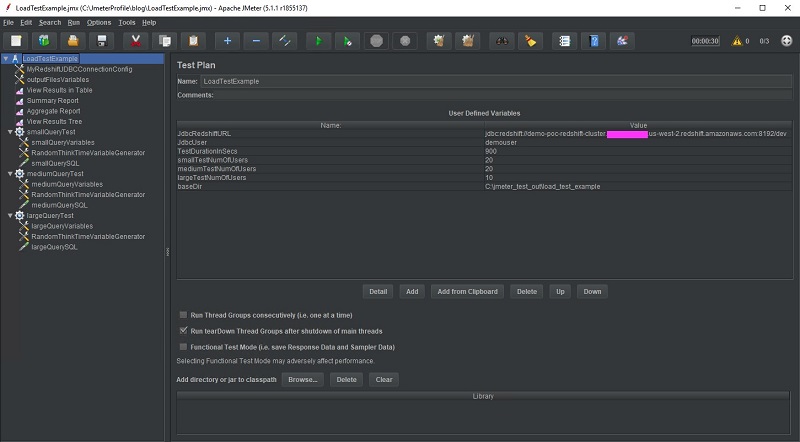
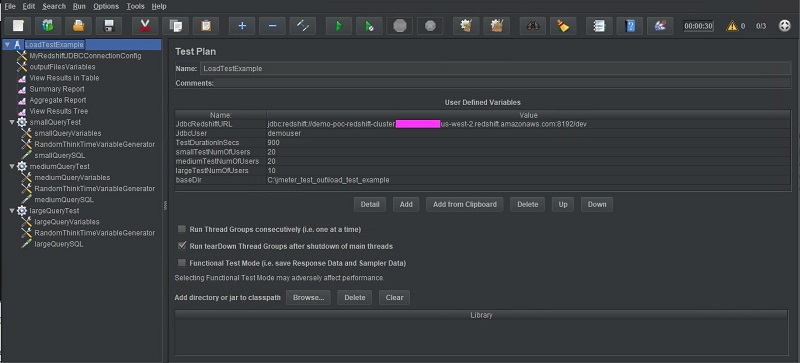
The following screenshot is the resulting load test.

The following screenshot is the resulting load test.

The following screenshot provides a close up of the building block tree.

The following screenshot provides a close up of the building block tree.

In the following sections, we examine each building block in greater detail.

Test Plan

The test plan serves as the parent container for our entire benchmark test, and we can change its name in the visual tree that appears in the Apache JMeter GUI by editing the Name field.

I take advantage of the User Defined Variables section to set my own custom variables that hold values needed by all components in the test case, such as the JDBC URL, test duration, and number of users submitting small, medium, and large queries. The baseDir variable is actually a variable that is intended to be embedded in other variables, rather than directly referenced by other test components. I left all other settings at their default on this page.

The baseDir variable is actually a variable that is intended to be embedded in other variables, rather than directly referenced by other test components.

JDBC Connection Configuration

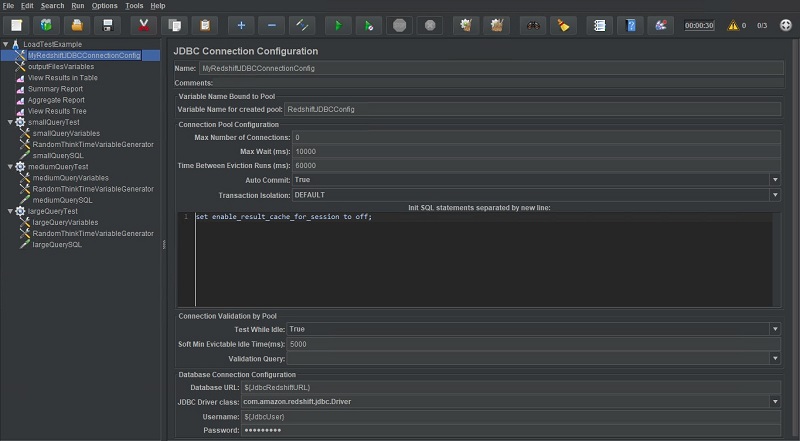
We use the JDBC Connection Configuration building block to create a database connection pool that is used by the simulated users to submit queries to Amazon Redshift. The value specified in Variable Name for created pool is the identifier that is used to reference this connection pool in other JMeter building blocks. In this example, I named it RedshiftJDBCConfig.

By setting the Max Number of Connections to 0, the connection pool can grow as large as it needs to. That may not be the desired behavior for all test scenarios, so be sure to set it as you see fit.

In the Init SQL statements section, I provide an example of how to use SQL to disable the result set cache in Amazon Redshift for every connection created, or perform other similar initialization code.

Towards the end, I input the database JDBC URL (which is actually a variable reference to a variable defined in the test plan), JDBC driver class name, and database username and password. I left all other fields at their default on this page.

I left all other fields at their default on this page.

User Defined Variables

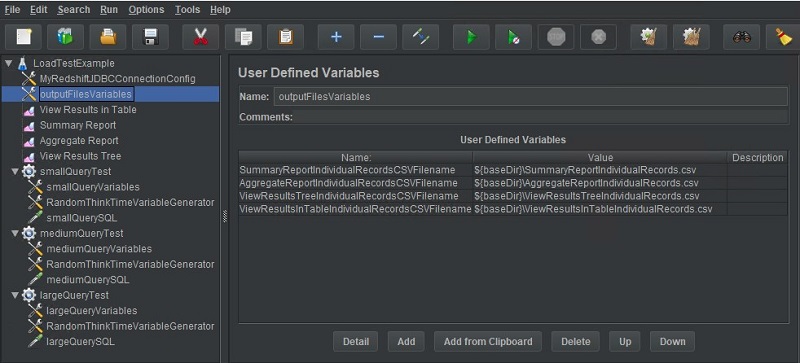
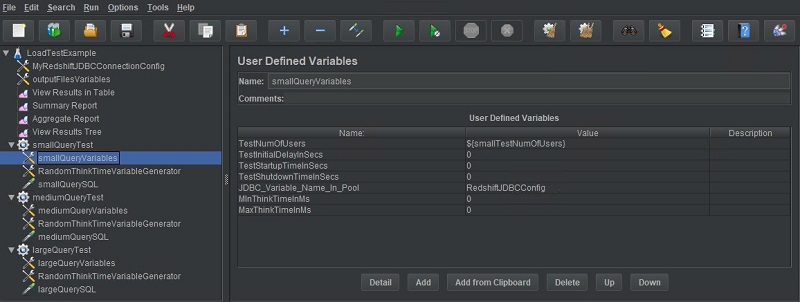
You can add a User Defined Variables building block in several places, and it’s best to use this capability to limit the scope of each variable. For this post, we use an instance of the User Defined Variables building block to hold the output file names of each listener in this test plan (if you look closely, you can see the values of these variables reference the baseDir variable, which was defined in our test plan). You can also notice three other instances of the User Defined Variables building block for the small, medium, and large thread groups—again so that the scope of variables is kept appropriately narrow.

You can add a User Defined Variables building block in several places, and it’s best to use this capability to limit the scope of each variable.

Listeners

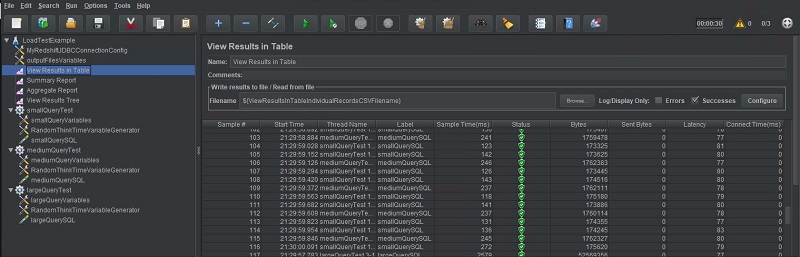
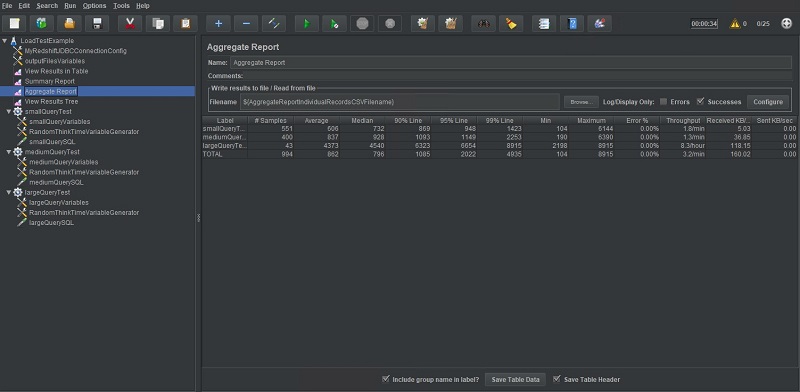
Listeners control where test output is written and how it’s processed. There are many different kinds of listeners that, for example, allow you to capture your test output as a tree, table, or graph. Other listeners can summarize and aggregate test metadata (such as the number of test samples submitted during the test). I choose to add several listeners in this test plan just for demonstration, but I have found the listeners Aggregate Report and View Results in Table to be most helpful to me. The following screenshot shows the View Results in Table output.

The following screenshot shows the View Results in Table output.

The following screenshot shows the Aggregate Report output.

The following screenshot shows the Aggregate Report output.

You can also save output from listeners after a test run to a different file through the JMeter menu.

Thread group: Ultimate Thread Group

A thread group can be thought of as a group of simulated users, which is why for this post, I create three separate thread groups: one to represent each of three previously mentioned user personas being simulated (small, medium, and large). Each thread group is named accordingly.

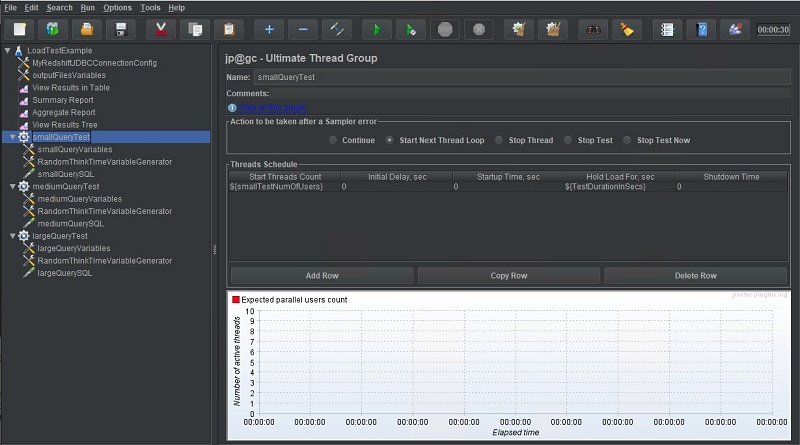
We use the Thread Schedule section to control how many users should be created and at what time interval. In this test, I chose to have all 20 small users created at start time without any delays. This is achieved by a one-row entry in the Thread Schedule and setting the Start Threads Count thread group property to 20 users (or the matching variable, as we do in the following screenshot).

We use the Thread Schedule section to control how many users should be created and at what time interval.

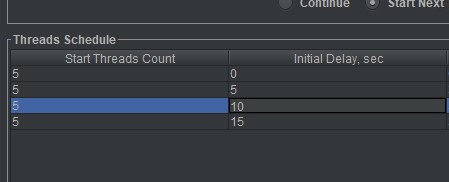
Alternatively, I could stagger user creation by creating multiple rows and setting the Initial Delay sec field to control each row’s startup delay. With the row entries in the following screenshot, an additional five users are created every 5 seconds.

With the row entries in the following screenshot, an additional five users are created every 5 seconds.

Thread group: User Defined Variables

An additional User Defined Variables instance is added to each of the three thread groups to hold the variables in their individual scope, or that would preferably be configurable at an individual thread group level. For this post, I make the JDBC Connection Configuration a variable so that it’s customizable for each individual thread group (JDBC_Variable_Name_In_Pool). This allows me to, for example, rapidly switch two different test clusters.

An additional User Defined Variables instance is added to each of the three thread groups to hold the variables in their individual scope.

JDBC Request

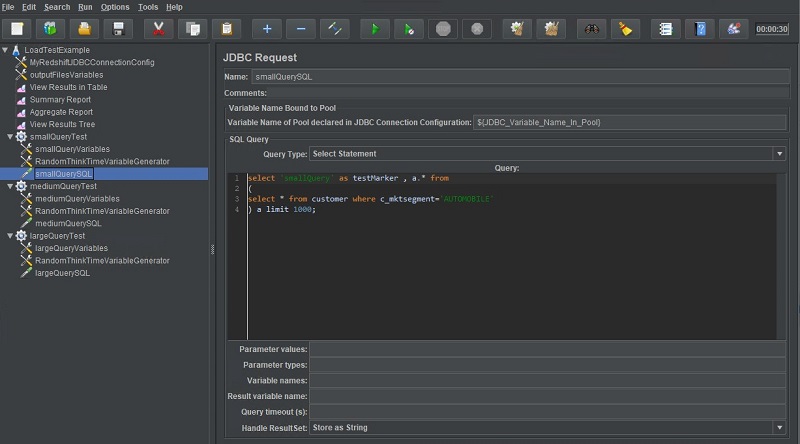
The JDBC Request can be thought of as the benchmark query or SQL test query to be submitted non-stop by each simulated user in this thread group. To configure this JDBC Request, I specified the appropriate JDBC Connection Configuration and some very simple test SQL. I could have also used Apache JMeter’s ability to parameterize queries so that they vary from one iteration to another using a predetermined set of parameter values. For example, for the SQL statement select * from customer where cust_id=<some value>, Apache JMeter could be configured to set the value in the filter clause to a randomly chosen value from a pre-compiled list of filter values for each sample submission. I left all other settings at their default.

The JDBC Request can be thought of as the benchmark query or SQL test query to be submitted non-stop by each simulated user in this thread group.

Apache JMeter (CLI)

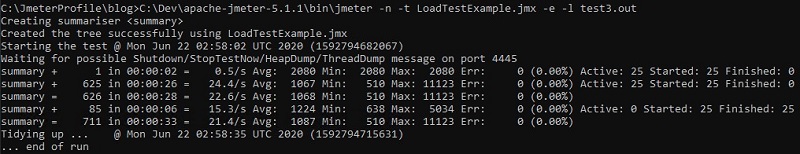
The Apache JMeter GUI saves test plans in .jmx files that can be used to run the same test plan in Apache JMeter’s console mode. The following CLI command demonstrates how you can use the LoadTestExample.jmx file that was created in the previous steps using the GUI to run the same load test:

> <jmeter_install_dir>\bin\jmeter -n -t LoadTestExample.jmx -e -l test.out

The sample output is from a 30-second run of LoadTestExample.jmx.

The sample output is from a 30-second run of LoadTestExample.jmx.

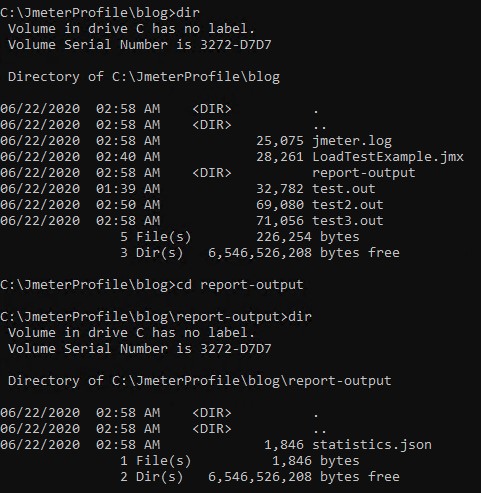
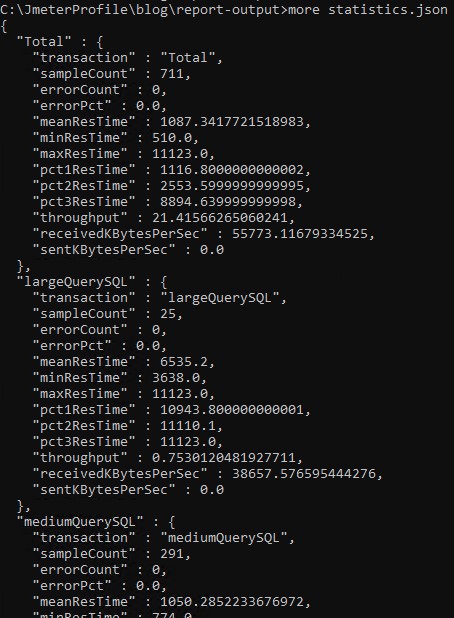
After the test has completed, several output files are created, such as a JMeter application log, query output files from the listeners (if any), and test statistics from listeners (if any). For this post, the statistical metrics captured for the test run are located in a JSON file inside the report-output directory. See the following screenshot.

For this post, the statistical metrics captured for the test run are located in a JSON file inside the report-output directory.

The \report-output\statistics.json file captures a lot of useful metrics, such as the total samples (like SQL queries) submitted during the test duration, achieved query throughput, and number of small, medium, and large queries and their individual throughput. The following screenshot shows a sampling of the data from statistics.json.

The following screenshot shows a sampling of the data from statistics.json.

Conclusion

In this series of posts, we discussed several recommended best practices for conducting high-quality benchmark tests. Some of the best practices represented core principles that span all the open-source tools discussed (such as consistency in testing methodology). In this particular post, we reviewed the strengths and appropriateness of Apache JMeter for conducting benchmark tests. I hope this series has been helpful, and strongly encourage current and prospective customers to reach out to me or other AWS colleagues if you wish to delve deeper.


About the Author

Asser Moustafa is an Analytics Specialist Solutions Architect at AWS based out of Dallas, Texas. He advises customers in the Americas on their Amazon Redshift and data lake architectures and migrations, starting from the POC stage to actual production deployment and maintenance

Setting up automated data quality workflows and alerts using AWS Glue DataBrew and AWS Lambda

Post Syndicated from Romi Boimer original https://aws.amazon.com/blogs/big-data/setting-up-automated-data-quality-workflows-and-alerts-using-aws-glue-databrew-and-aws-lambda/

Proper data management is critical to successful, data-driven decision-making. An increasingly large number of customers are adopting data lakes to realize deeper insights from big data. As part of this, you need clean and trusted data in order to gain insights that lead to improvements in your business. As the saying goes, garbage in is garbage out—the analysis is only as good as the data that drives it.

Organizations today have continuously incoming data that may develop slight changes in schema, quality, or profile over a period of time. To ensure data is always of high quality, we need to consistently profile new data, evaluate that it meets our business rules, alert for problems in the data, and fix any issues. In this post, we leverage AWS Glue DataBrew, a visual data preparation tool that makes it easy to profile and prepare data for analytics and machine learning (ML). We demonstrate how to use DataBrew to publish data quality statistics and build a solution around it to automate data quality alerts.

Overview of solution

In this post, we walk through a solution that sets up a recurring profile job to determine data quality metrics and, using your defined business rules, report on the validity of the data. The following diagram illustrates the architecture.

We’ll walk through a solution that takes sets up a recurring Profile job to determine data quality metrics, and using your defined business rules.

The steps in this solution are as follows:

  1. Periodically send raw data to Amazon Simple Storage Service (Amazon S3) for storage.
  2. Read the raw data in Amazon S3 and generate a scheduled DataBrew profile job to determine data quality.
  3. Write the DataBrew profile job output to Amazon S3.
  4. Trigger an Amazon EventBridge event after job completion.
  5. Invoke an AWS Lambda function based on the event, which reads the profile output from Amazon S3 and determines whether the output meets data quality business rules.
  6. Publish the results to an Amazon Simple Notification Service (Amazon SNS) topic.
  7. Subscribe email addresses to the SNS topic to inform members of your organization.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Deploying the solution

For a quick start of this solution, you can deploy the provided AWS CloudFormation stack. This creates all the required resources in your account (us-east-1 Region). Follow the rest of this post for a deeper dive into the resources.

  1. Choose Launch Stack:

  1. In Parameters, for Email, enter an email address that can receive notifications.
  2. Scroll to the end of the form and select I acknowledge that AWS CloudFormation might create IAM resources.
  3. Choose Create stack.

It takes a few minutes for the stack creation to complete; you can follow progress on the Events tab.

  1. Check your email inbox and choose Confirm subscription in the email from AWS Notifications.

The default behavior of the deployed stack runs the profile on Sundays. You can start a one-time run from the DataBrew console to try out the end-to-end solution.

Setting up your source data in Amazon S3

In this post, we use an open dataset of New York City Taxi trip record data from The Registry of Open Data on AWS. This dataset represents a collection of CSV files defining trips taken by taxis and for-hire vehicles in New York City. Each record contains the pick-up and drop-off IDs and timestamps, distance, passenger count, tip amount, fair amount, and total amount. For the purpose of illustration, we use a static dataset; in a real-world use case, we would use a dataset that is refreshed at a defined interval.

You can download the sample dataset (us-east-1 Region) and follow the instructions for this solution, or use your own data that gets dumped into your data lake on a recurring basis. We recommend creating all your resources in the same account and Region. If you use the sample dataset, choose us-east-1.

Creating a DataBrew profile job

To get insights into the quality of our data, we run a DataBrew profile job on a recurring basis. This profile provides us with a statistical summary of our dataset, including value distributions, sparseness, cardinality, and type determination.

Connecting a DataBrew dataset

To connect your dataset, complete the following steps:

  1. On the DataBrew console, in the navigation pane, choose Datasets.
  2. Choose Connect new dataset.
  3. Enter a name for the dataset.
  4. For Enter your source from S3, enter the S3 path of your data source. In our case, this is s3://nyc-tlc/misc/.
  5. Select your dataset (for this post, we choose the medallions trips dataset FOIL_medallion_trips_june17.csv).

  1. Scroll to the end of the form and choose Create dataset.

Creating the profile job

You’re now ready to create your profile job.

  1. In the navigation pane, choose Datasets.
  2. On the Datasets page, select the dataset that you created in the previous step. The row in the table should be highlighted.
  3. Choose Run data profile.
  4. Select Create profile job.
  5. For Job output settings, enter an S3 path as destination for the profile results. Make sure to note down the S3 bucket and key, because you use it later in this tutorial.
  6. For Permissions, choose a role that has access to your input and output S3 paths. For details on required permissions, see DataBrew permission documentation.
  7. On the Associate schedule drop-down menu, choose Create new schedule.
  8. For Schedule name, enter a name for the schedule.
  9. For Run frequency, choose a frequency based on the time and rate at which your data is refreshed.
  10. Choose Add.

  1. Choose Create and run job.

The job run on sample data typically takes 2 minutes to complete.

Exploring the data profile

Now that we’ve run our profile job, we can expose insightful characteristics about our dataset. We can also review the results of the profile through the visualizations of the DataBrew console or by reading the raw JSON results in our S3 bucket.

The profile analyzes both at a dataset level and column level granularity. Looking at our column analytics for String columns, we have the following statistics:

  • MissingCount – The number of missing values in the dataset
  • UniqueCount – The number of unique values in the dataset
  • Datatype – The data type of the column
  • CommonValues – The top 100 most common strings and their occurrences
  • Min – The length of the shortest String value
  • Max – The length of the longest String value
  • Mean – The average length of the values
  • Median – The middle value in terms of character count
  • Mode – The most common String value length
  • StandardDeviation – The standard deviation for the lengths of the String values

For numerical columns, we have the following:

  • Min – The minimum value
  • FifthPercentile – The value that represents 5th percentile (5% of values fall below this and 95% fall above)
  • Q1 – The value that represents 25th percentile (25% of values fall below this and 75% fall above)
  • Median – The value that represents 50th percentile (50% of values fall below this and 50% fall above)
  • Q3 – The value that represents 75th percentile (75% of values fall below this and 25% fall above)
  • NinetyFifthPercentile – The value that represents 95th percentile (95% of values fall below this and 5% fall above)
  • Max – The highest value
  • Range – The difference between the highest and lowest values
  • InterquartileRange – The range between the 25th percentile and 75th percentile values
  • StandardDeviation – The standard deviation of the values (measures the variation of values)
  • Kurtosis – The kurtosis of the values (measures the heaviness of the tails in the distribution)
  • Skewness – The skewness of the values (measures symmetry in the distribution)
  • Sum – The sum of the values
  • Mean – The average of the values
  • Variance – The variance of the values (measures divergence from the mean)
  • CommonValues – A list of the most common values in the column and their occurrence count
  • MinimumValues – A list of the 5 minimum values in the list and their occurrence count
  • MaximumValues – A list of the 5 maximum values in the list and their occurrence count
  • MissingCount – The number of missing values
  • UniqueCount – The number of unique values
  • ZerosCount – The number of zeros
  • Datatype – The datatype of the column
  • Min – The minimum value
  • Max – The maximum value
  • Median – The middle value
  • Mean – The average value
  • Mode – The most common value 

Finally, at a dataset level, we have an overview of the profile as well as cross-column analytics:

  • DatasetName – The name of the dataset the profile was run on
  • Size – The size of the data source in KB
  • Source – The source of the dataset (for example, Amazon S3)
  • Location – The location of the data source
  • CreatedBy – The ARN of the user that created the profile job
  • SampleSize – The number of rows used in the profile
  • MissingCount – The total number of missing cells
  • DuplicateRowCount – The number of duplicate rows in the dataset
  • StringColumnsCount – The number of columns that are of String type
  • NumberColumnsCount – The number of columns that are of numeric type
  • BooleanColumnsCount – The number of columns that are of Boolean type
  • MissingWarningCount – The number of warnings on columns due to missing values
  • DuplicateWarningCount – The number of warnings on columns due to duplicate values
  • JobStarted – A timestamp indicating when the job started
  • JobEnded – A timestamp indicating when the job ended
  • Correlations – The statistical relationship between columns

By default, the DataBrew profile is run on a 20,000-row First-N sample of your dataset. If you want to increase the limit and run the profile on your entire dataset, send a request to [email protected].

Creating an SNS topic and subscription

Amazon SNS allows us to deliver messages regarding the quality of our data reliably and at scale. For this post, we create an SNS topic and subscription. The topic provides us with a central communication channel that we can broadcast to when the job completes, and the subscription is then used to receive the messages published to our topic. For our solution, we use an email protocol in the subscription in order to send the profile results to the stakeholders in our organization.

Creating the SNS topic

To create your topic, complete the following steps:

  1. On the Amazon SNS console, in the navigation pane, choose Topics.
  2. Choose Create topic.
  3. For Type, select Standard.
  4. For Name, enter a name for the topic.

For Name, enter a name for the topic.

  1. Choose Create topic.
  2. Take note of the ARN in the topic details to use later.

Creating the SNS subscription

To create your subscription, complete the following steps:

  1. In the navigation pane, choose Subscriptions.
  2. Choose Create subscription.
  3. For Topic ARN, choose the topic that you created in the previous step.
  4. For Protocol, choose Email.
  5. For Endpoint, enter an email address that can receive notifications.

For Endpoint, enter an email address that can receive notifications.

  1. Choose Create subscription.
  2. Check your email inbox and choose Confirm subscription in the email from AWS Notifications.

Creating a Lambda function for business rule validation

The profile has provided us with an understanding of the characteristics of our data. Now we can create business rules that ensure we’re consistently monitoring the quality our data.

For our sample taxi dataset, we will validate the following:

  • Making sure the pu_loc_id and do_loc_id columns meet a completeness rate of 90%.
  • If more than 10% of the data in those columns is missing, we’ll notify our team that the data needs to be reviewed.

Creating the Lambda function

To create your function, complete the following steps:

  1. On the Lambda console, in the navigation pane, choose Functions.
  2. Choose Create function.
  3. For Function name¸ enter a name for the function.
  4. For Runtime, choose the language you want to write the function in. If you want to use the code sample provided in this tutorial, choose Python 3.8.

For Runtime, choose the language you want to write the function in. If you want to use the code sample provided in this tutorial, choose Python 3.8.

  1. Choose Create function.

Adding a destination to the Lambda function

You now add a destination to your function.

  1. On the Designer page, choose Add destination.
  2. For Condition, select On success.
  3. For Destination type, choose SNS topic.
  4. For Destination, choose the SNS topic from the previous step.

For Destination, choose the SNS topic from the previous step.

  1. Choose Save.

Authoring the Lambda function

For the function code, enter the following sample code or author your own function that parses the DataBrew profile job JSON and verifies it meets your organization’s business rules.

If you use the sample code, make sure to fill in the values of the required parameters to match your configuration:

  • topicArn – The resource identifier for the SNS topic. You find this on the Amazon SNS console’s topic details page (for example, topicArn = 'arn:aws:sns:us-east-1:012345678901:databrew-profile-topic').
  • profileOutputBucket – The S3 bucket the profile job is set to output to. You can find this on the DataBrew console’s job details page (for example, profileOutputBucket = 'taxi-data').
  • profileOutputPathKey – The S3 key the profile job is set to output to. You can find this on the DataBrew console’s job details page (for example, profileOutputPathKey = profile-out/'). If you’re writing directly to an S3 bucket, keep this as an empty String (profileOutputPathKey = '').
    import json
    import boto3
    
    sns = boto3.client('sns')
    s3 = boto3.client('s3')
    s3Resource = boto3.resource('s3')
    
    # === required parameters ===
    topicArn = 'arn:aws:sns:<YOUR REGION>:<YOUR ACCOUNT ID>:<YOUR TOPIC NAME>'
    profileOutputBucket = '<YOUR S3 BUCKET NAME>'
    profileOutputPrefix = '<YOUR S3 KEY>'
    
    def verify_completeness_rule(bucket, key):
        # completeness threshold set to 10%
        threshold = 0.1
        
        # parse the DataBrew profile
        profileObject = s3.get_object(Bucket = bucket, Key = key)
        profileContent = json.loads(profileObject['Body'].read().decode('utf-8'))
        
        # verify the completeness rule is met on the pu_loc_id and do_loc_id columns
        for column in profileContent['columns']:
            if (column['name'] == 'pu_loc_id' or column['name'] == 'do_loc_id'):
                if ((column['missingValuesCount'] / profileContent['sampleSize']) > threshold):
                    # failed the completeness check
                    return False
    
        # passed the completeness check
        return True
    
    def lambda_handler(event, context):
        jobRunState = event['detail']['state']
        jobName = event['detail']['jobName'] 
        jobRunId = event['detail']['jobRunId'] 
        profileOutputKey = ''
    
        if (jobRunState == 'SUCCEEDED'):
            profileOutputPostfix = jobRunId[3:] + '.json'
    
            bucket = s3Resource.Bucket(profileOutputBucket)
            for object in bucket.objects.filter(Prefix = profileOutputPrefix):
                if (profileOutputPostfix in object.key):
                    profileOutputKey = object.key
            
            if (verify_completeness_rule(profileOutputBucket, profileOutputKey)):
                message = 'Nice! Your profile job ' + jobName + ' met business rules. Head to https://console.aws.amazon.com/databrew/ to view your profile.' 
                subject = 'Profile job ' + jobName + ' met business rules' 
            else:
                message = 'Uh oh! Your profile job ' + jobName + ' did not meet business rules. Head to https://console.aws.amazon.com/databrew to clean your data.'
                subject = 'Profile job ' + jobName + ' did not meet business rules'
        
        else:
            # State is FAILED, STOPPED, or TIMEOUT - intervention required
            message = 'Uh oh! Your profile job ' + jobName + ' is in state ' + jobRunState + '. Check the job details at https://console.aws.amazon.com/databrew#job-details?job=' + jobName
            subject = 'Profile job ' + jobName + ' in state ' + jobRunState
            
        response = sns.publish (
            TargetArn = topicArn,
            Message = message,
            Subject = subject
        )
    
        return {
            'statusCode': 200,
            'body': json.dumps(response)
        }

Updating the Lambda function’s permissions

In this final step of configuring your Lambda function, you update your function’s permissions.

  1. In the Lambda function editor, choose the Permissions tab.
  2. For Execution role, choose the role name to navigate to the AWS Identity and Access Management (IAM) console.
  3. In the Role summary, choose Add inline policy.
  4. For Service, choose S3.
  5. For Actions, under List, choose ListBucket.
  6. For Actions, under Read, choose Get Object.
  7. In the Resources section, for bucket, choose Add ARN.
  8. Enter the bucket name you used for your output data in the create profile job step.
  9. In the modal, choose Add.
  10. For object, choose Add ARN.
  11. For bucket name, enter the bucket name you used for your output data in the create profile job step and append the key (for example, taxi-data/profile-out).
  12. For object name, choose Any. This provides read access to all objects in the chosen path.
  13. In the modal, choose Add.
  14. Choose Review policy.
  15. On the Review policy page, enter a name.
  16. Choose Create policy. 

We return to the Lambda function to add a trigger later, so keep the Lambda service page open in a tab as you continue to the next step, adding an EventBridge rule.

Creating an EventBridge rule for job run completion

EventBridge is a serverless event bus service that we can configure to connect applications. For this post, we configure an EventBridge rule to route DataBrew job completion events to our Lambda function. When our profile job is complete, the event triggers the function to process the results.

Creating the EventBridge rule

To create our rule in EventBridge, complete the following steps:

  1. On the EventBridge console, in the navigation pane, choose Rules.
  2. Choose Create rule.
  3. Enter a name and description for the rule.
  4. In the Define pattern section, select Event pattern.
  5. For Event matching pattern, select Pre-defined pattern by service.
  6. For Service provider, choose AWS.
  7. For Service name, choose AWS Glue DataBrew.
  8. For Event type, choose DataBrew Job State Change.
  9. For Target, choose Lambda function.
  10. For Function, choose the name of the Lambda function you created in the previous step.

For Function, choose the name of the Lambda function you created in the previous step.

  1. Choose Create.

Adding the EventBridge rule as the Lambda function trigger

To add your rule as the function trigger, complete the following steps:

  1. Navigate back to your Lambda function configuration page from the previous step.
  2. In the Designer, choose Add trigger.
  3. For Trigger configuration, choose EventBridge (CloudWatch Events).
  4. For Rule, choose the EventBridge rule you created in the previous step.

For Rule, choose the EventBridge rule you created in the previous step.

  1. Choose Add.

Testing your system

That’s it! We’ve completed all the steps required for this solution to run periodically. To give it an end-to-end test, we can run our profile job once and wait for the resulting email to get our results.

  1. On the DataBrew console, in the navigation pane, choose Jobs.
  2. On the Profile jobs tab, select the job that you created. The row in the table should be highlighted.
  3. Choose Run job.
  4. In the Run job modal, choose Run job.

A few minutes after the job is complete, you should receive an email notifying you of the results of your business rule validation logic.

A few minutes after the job is complete, you should receive an email notifying you of the results of your business rule validation logic.

Cleaning up

To avoid incurring future charges, delete the resources created during this walkthrough.

Conclusion

In this post, we walked through how to use DataBrew alongside Amazon S3, Lambda, EventBridge, and Amazon SNS to automatically send data quality alerts. We encourage you to extend this solution by customizing the business rule validation to meet your unique business needs.


About the Authors

Romi Boimer is a Sr. Software Development Engineer at AWS and a technical lead for AWS Glue DataBrew. She designs and builds solutions that enable customers to efficiently prepare and manage their data. Romi has a passion for aerial arts, in her spare time she enjoys fighting gravity and hanging from fabric.


Shilpa Mohan is a Sr. UX designer at AWS and leads the design of AWS Glue DataBrew. With over 13 years of experience across multiple enterprise domains, she is currently crafting products for Database, Analytics and AI services for AWS. Shilpa is a passionate creator, she spends her time creating anything from content, photographs to crafts.

Sharing Amazon Redshift data securely across Amazon Redshift clusters for workload isolation

Post Syndicated from Harsha Tadiparthi original https://aws.amazon.com/blogs/big-data/sharing-amazon-redshift-data-securely-across-amazon-redshift-clusters-for-workload-isolation/

Amazon Redshift data sharing allows for a secure and easy way to share live data for read purposes across Amazon Redshift clusters. Amazon Redshift is a fast, fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing business intelligence (BI) tools. It allows you to run complex analytic queries against terabytes to petabytes of structured data, using sophisticated query optimization, columnar storage on high-performance storage, and massively parallel query runs.

In this post, we discuss how to use Amazon Redshift data sharing to achieve workload isolation across diverse analytics use cases and achieve business-critical SLAs. For more information about this new feature, see Announcing Amazon Redshift data sharing (preview).

How to use Amazon Redshift data sharing

Amazon Redshift data sharing allows a producer cluster to share data objects to one or more Amazon Redshift consumer clusters for read purposes without having to copy the data. With this approach, workloads isolated to different clusters can share and collaborate frequently on data to drive innovation and offer value-added analytic services to your internal and external stakeholders. You can share data at many levels, including databases, schemas, tables, views, columns, and user-defined functions, to provide fine-grained access controls that can be tailored for different users and businesses that all need access to Amazon Redshift data.

Data sharing between Amazon Redshift clusters is a two-step process. First, the producer cluster administrator that wants to share data creates an Amazon Redshift data share, a new named object introduced with this release to serve as a unit of sharing. The producer cluster adds the needed database objects such as schemas, tables, and views to the data share and specifies a list of consumer clusters with which to share the data share. Following that, privileged users on consumer clusters create an Amazon Redshift local database reference from the data share made available to them and grant permissions on the database objects to appropriate users and groups. Users and groups can then list the shared objects as part of the standard metadata queries and start querying immediately.

Solution overview

For this post, we use a use case in which the producer cluster is a central ETL cluster hosting enterprise sales data, a 3 TB Cloud DW benchmark dataset based on the TPC-DS benchmark dataset. This cluster serves multiple BI and data science clusters purpose-built for distinct business groups within the organization. One such group is the sales BI team, who runs BI reports using customer sales data created in the central ETL cluster and joined with the product reviews dataset that they loaded into the BI cluster they manage.

This approach helps the sales BI team isolate data lifecycle management between the enterprise sales dataset in the ETL producer from the product reviews data that they fully manage in the BI consumer cluster to simplify data stewardship. It also allows for agility, allows sizing clusters independently to provide workload isolation, and creates a simple cost charge-back model.

As depicted in the following diagram, the central ETL cluster etl_cluster hosts the sales data in a schema named sales. We demonstrate how to build the semantic layer later in this post. A superuser in etl_cluster then creates a data share named salesdatashare, adds the bi_semantic schema and all objects in that schema to the data share, and grants usage permissions to the BI consumer cluster named bi_cluster. Keep in mind that a data share is simply a metadata container and represents what data is shared from producer to consumer. No data is actually moved.

As depicted in the following diagram, the central ETL cluster etl_cluster hosts the sales data in a schema named sales and performs transformations to create a semantic layer required for BI reports in a new schema named bi_semantic.

The superuser in the BI consumer cluster creates a local database reference named sales_semantic from the data share (step 2 in the preceding diagram). The BI users use the product reviews dataset in the local schema named product_reviews and join with bi_semantic data for reporting purposes (step 3).

You can find the script in the products review dataset, which we use in this post to load the dataset into bi_cluster. You can load the DW benchmark dataset into etl_cluster using this github link. Loading these datasets into the respective Amazon Redshift clusters is outside the scope of this post, and is a prerequisite to following the instructions we outline.

The following diagram depicts the cloud DW benchmark data model used.

The following diagram depicts the cloud DW benchmark data model used.

The following table summarizes the data.

Table Name Rows
STORE_SALES 8,639,936,081
CUSTOMER_ADDRESS 15,000,000
CUSTOMER 30,000,000
CUSTOMER_DEMOGRAPHICS 1,920,800
ITEM 360,000
DATE_DIM 73,049

Building a BI semantic layer

A BI semantic layer is a representation of enterprise data in a way that simplifies BI reporting requirements and offers better performance. In our use case, the BI semantic layer transforms sales data to create a customer denormalized dataset and another dataset for all store sales by product in a given year. The following queries are run on the etl_cluster to create the BI semantic layer.

  1. Create a new schema to host BI semantic tables with the following SQL:
    Create schema bi_semantic;

  2. Create a denormalized customer view with select columns required for sales BI team:
    create view bi_semantic.customer_denorm 
    as
    select
    	c_customer_sk,
    	c_customer_id,
    	c_birth_year,
    	c_birth_country,
    	c_last_review_date_sk,
    	ca_city,
    	ca_state,
    	ca_zip,
    	ca_country,
    	ca_gmt_offset,
    	cd_gender,
    	cd_marital_status,
    	cd_education_status
    from sales.customer c, sales.customer_address ca, sales.customer_demographics cd
    where
    c.c_current_addr_sk=ca.ca_address_sk
    and c.c_current_cdemo_sk=cd.cd_demo_sk;

  1. Create a second view for all product sales with columns required for BI team:
    create view bi_semantic.product_sales
    as 
    select 
    	i_item_id,
    	i_product_name,
    	i_current_price,
    	i_wholesale_cost,
    	i_brand_id,
    	i_brand,
    	i_category_id,
    	i_category,
    	i_manufact,
    	d_date,
    	d_moy,
    	d_year,
    	d_quarter_name,
    	ss_customer_sk,
    	ss_store_sk,
    	ss_sales_price,
    	ss_list_price,
    	ss_net_profit,
    	ss_quantity,
    	ss_coupon_amt
    from sales.store_sales ss, sales.item i, sales.date_dim d
    where ss.ss_item_sk=i.i_item_sk
    and ss.ss_sold_date_sk=d.d_date_sk;

Sharing data across Amazon Redshift clusters

Now, let’s share the bi_semantic schema in the etl_cluster with the bi _cluster.

  1. Create a data share in the etl_cluster using the following command when connected to the etl_cluster. The producer cluster superuser and database owners can create data share objects. By default, PUBLICACCESSIBLE is false. If the producer cluster is publicly accessible, you can add PUBLICACCESSIBLE = true to the following command:
    CREATE DATASHARE SalesDatashare;

  1. Add the BI semantic views to the data share. To add objects to the data share, add the schema before adding objects. Use ALTER DATASHARE to share the entire schema; to share tables, views, and functions in a given schema; and to share objects from multiple schemas:
    ALTER DATASHARE SalesDatashare ADD SCHEMA bi_semantic;
    ALTER DATASHARE SalesDatashare ADD ALL TABLES IN SCHEMA bi_semantic;

The next step requires a cluster namespace GUID from the bi_cluster. One way to find the namespace value of a cluster is to run the SQL statement select current_namespace when connected to the bi_cluster. Another way is on the Amazon Redshift console: choose your Amazon Redshift consumer cluster, and find the value under Namespace located in the General information section.

  1. Add consumers to the data share using the following command:
    GRANT USAGE ON DATASHARE SalesDatashare TO NAMESPACE '1m137c4-1187-4bf3-8ce2-e710b7100eb2';

  1. View the list of the objects added to the share using the following command. The share type is outbound on the producer cluster.
    DESC DATASHARE salesdatashare;

The following screenshot shows our list of objects.

The following screenshot shows our list of objects.

Consuming the data share from the consumer BI Amazon Redshift cluster

From the bi_cluster, let’s review, consume, and set permissions on the data share for end-user consumption.

  1. On the consumer BI cluster, view the data shares using the following command as any user:
    SHOW DATASHARES;

The following screenshot shows our results. Consumers should be able to see the objects within the incoming share but not the full list of consumers associated with the share. For more information about querying the metadata of shares, see DESC DATASHARE.

The following screenshot shows our results.

  1. Start the consumption by creating a local database from the salesdatashare. Cluster users with the permission to do so can create a database from the shares. We use the namespace from the etl_cluster.
    CREATE DATABASE Sales_semantic from DATASHARE SalesDatashare OF NAMESPACE '45b137c4-1287-4vf3-8cw2-e710b7138nd9'; 

Consumers should be able to see databases that they created from the share, along with the databases local to the cluster, at any point by querying SVV_REDSHIFT* tables. Data share objects aren’t available for queries until a local database reference is created using a create database statement.

  1. Run the following command to list the databases in bi_cluster:
    select * from svv_redshift_databases;

The following screenshot shows that both the local and shared databases are listed so that you can explore and navigate metadata for shared datasets.

The following screenshot shows that both the local and shared databases are listed so that you can explore and navigate metadata for shared datasets.

  1. Grant usage on the database to bi_group, where bi_group is a local Amazon Redshift group with BI users added to that group:
    GRANT USAGE ON DATABASE sales_semantic TO bi_group;

Querying as the BI user

In this section, you connect as a user in the bi_group who got access to the shared data. The user is still connected to the local database on the bi_cluster but can query the shared data via the new cross-database query functionality in Amazon Redshift.

  1. Review the list of objects in the share by running the following SQL:
    SELECT schema_name, table_name, table_type FROM  svv_redshift_tables
         where database_name = 'sales_semantic'

The following screenshot shows our results.

The following screenshot shows our results.

  1. Review the list of columns in the customer_denorm view::
    SELECT * FROM  svv_redshift_columns 
       where database_name = 'sales_semantic' and table_name = 'customer_denorm';

The following screenshot shows our results.

The following screenshot shows our results.

  1. Query the shared objects using three-part notation just like querying any other local database object, using a notation <database>.<schema>.<view/table>:
    select count(*) from sales_semantic.bi_semantic.customer_denorm;

Following is your result:

28950139

  1. Analyze the local product reviews data by joining the shared customer_denorm data to identify the top ratings by customer states for this BI report:
    SELECT PR.product_category, c.ca_state AS customer_state,
                  count(PR.star_rating) AS cnt
          FROM product_reviews.amazon_reviews PR,               --local data
               sales_semantic.bi_semantic.customer_denorm  C    –-shared data
          WHERE  PR.customer_id = C.c_customer_sk
             AND PR.marketplace = 'US'
          GROUP BY 1, 2
          order by cnt desc
          Limit 10;

The following screenshot shows our results.

The following screenshot shows our results.

Adding a data science consumer

Now, let’s assume the company has decided to spin up a data science team to help with new sales strategies, and this team performs analytics on the sales data. The data science team is new and has very different access patterns and SLA requirements compared to the BI team. Thanks to the data sharing feature, onboarding new use cases such as this is easy.

We add a data science consumer cluster named ds_cluster. Because the data science users need access to data in salesdatashare, the superuser in the etl_cluster can simply grant access to the ds_cluster by adding them as another consumer for the share without moving any data:

GRANT USAGE ON DATASHARE SalesDatashare TO NAMESPACE ''1h137c4-1187-4w53-8de2-e710b7100es2';

The following diagram shows our updated architecture with the data science consumer (step 4).

The following diagram shows our updated architecture with the data science consumer (step 4).

This way, multiple clusters of different sizes can access the same dataset and isolate workloads to meet their SLA requirements. Users in these respective clusters are granted access to shared objects to meet their stringent security requirements. The producer keeps control of the data and at any point can remove certain objects from the share or remove access to the share for any of these clusters, and the consumers immediately lose access to the data. Also, as more data is ingested into the producer cluster, the consumer sees transactionally consistent data instantly.

Monitoring and security

Amazon Redshift offers comprehensive auditing capabilities using system tables and AWS CloudTrail to allow you to monitor the data sharing permissions and usage across all the consumers and revoke access instantly when necessary. The permissions are granted by the superusers from both the producer and the consumer clusters to define who gets access to what objects, similar to the grant commands used in the earlier scenario. You can use the following commands to audit the usage and activities for the data share.

Track all changes to the data share and the shared database imported from the data share with the following code:

Select username, share_name, recordtime, action, 
         share_object_type, share_object_name 
  from svl_datashare_change_log
   order by recordtime desc;

The following screenshot shows our results.

The following screenshot shows our results.

Track data share access activity (usage), which is relevant only on the producer, with the following code:

Select * from svl_datashare_usage;

The following screenshot shows our results.

The following screenshot shows our results.

Summary

Amazon Redshift data sharing provides workload isolation by allowing multiple consumers to share data seamlessly without the need to unload and load data. We also presented a step-by-step guide for securely sharing data from a producer to multiple consumer clusters.


About the Authors

Harsha Tadiparthi is a Specialist Sr. Solutions Architect, AWS Analytics. He enjoys solving complex customer problems in Databases and Analytics and delivering successful outcomes. Outside of work, he loves to spend time with his family, watch movies, and travel whenever possible.


Harshida Patel is a Specialist Sr. Solutions Architect, Analytics with AWS.

Accelerating Amazon Redshift federated query to Amazon Aurora MySQL with AWS CloudFormation

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/accelerating-amazon-redshift-federated-query-to-amazon-aurora-mysql-with-aws-cloudformation/

Amazon Redshift federated query allows you to combine data from one or more Amazon Relational Database Service (Amazon RDS) for MySQL and Amazon Aurora MySQL databases with data already in Amazon Redshift. You can also combine such data with data in an Amazon Simple Storage Service (Amazon S3) data lake.

This post shows you how to set up Aurora MySQL and Amazon Redshift with a TPC-DS dataset so you can take advantage of Amazon Redshift federated query using AWS CloudFormation. You can use the environment you set up in this post to experiment with various use cases in the post Announcing Amazon Redshift federated querying to Amazon Aurora MySQL and Amazon RDS for MySQL.

Benefits of using CloudFormation templates

The standard workflow for setting up Amazon Redshift federated query involves six steps. For more information, see Querying data with federated queries in Amazon Redshift. With a CloudFormation template, you can condense these manual procedures into a few steps listed in a text file. The declarative code in the file captures the intended state of the resources that you want to create and allows you to automate the setup of AWS resources to support Amazon Redshift federated query. You can further enhance this template to become the single source of truth for your infrastructure.

A CloudFormation template acts as an accelerator. It helps you automate the deployment of technology and infrastructure in a safe and repeatable manner across multiple Regions and accounts with the least amount of effort and time.

Architecture overview

The following diagram illustrates the solution architecture.

The following diagram illustrates the solution architecture.

The CloudFormation template provisions the following components in the architecture:

  • VPC
  • Subnets
  • Route tables
  • Internet gateway
  • Amazon Linux bastion host
  • Secrets
  • Aurora for MySQL cluster with TPC-DS dataset preloaded
  • Amazon Redshift cluster with TPC-DS dataset preloaded
  • Amazon Redshift IAM role with required permissions

Prerequisites

Before you create your resources in AWS CloudFormation, you must complete the following prerequisites:

Setting up resources with AWS CloudFormation

This post provides a CloudFormation template as a general guide. You can review and customize it to suit your needs. Some of the resources that this stack deploys incur costs when in use.

To create your resources, complete the following steps:

  1. Sign in to the console.
  2. Choose the us-east-1 Region in which to create the stack.
  3. Choose Launch Stack:
  4. Choose Next.

This automatically launches AWS CloudFormation in your AWS account with a template. It prompts you to sign in as needed. You can view the CloudFormation template from within the console.

  1. For Stack name, enter a stack name.
  2. For Session, leave as the default.
  3. For ec2KeyPair, choose the key pair you created earlier.
  4. Choose Next.

This automatically launches AWS CloudFormation in your AWS account with a template.

  1. On the next screen, choose Next.
  2. Review the details on the final screen and select I acknowledge that AWS CloudFormation might create IAM resources.
  3. Choose Create.

Stack creation can take up to 45 minutes.

  1. After the stack creation is complete, on the Outputs tab of the stack, record the value of the key for the following components, which you use in a later step:
  • AuroraClusterEndpoint
  • AuroraSecretArn
  • RedshiftClusterEndpoint
  • RedshiftClusterRoleArn

As of this writing, this feature is in public preview. You can create a snapshot of your Amazon Redshift cluster created by the stack and restore the snapshot as a new cluster in the sql_preview maintenance track with the same configuration.

You can create a snapshot of your Amazon Redshift cluster created by the stack and restore the snapshot as a new cluster

You’re now ready to log in to both the Aurora MySQL and Amazon Redshift cluster and run some basic commands to test them.

Logging in to the clusters using the Amazon Linux bastion host

The following steps assume that you use a computer with an SSH client to connect to the bastion host. For more information about connecting using various clients, see Connect to your Linux instance.

  1. Move the private key of the EC2 key pair (that you saved previously) to a location on your SSH client, where you are connecting to the Amazon Linux bastion host.
  2. Change the permission of the private key using the following code, so that it’s not publicly viewable:
    chmod 400 <private key file name; for example, bastion-key.pem>

  1. On the Amazon EC2 console, choose Instances.
  2. Choose the Amazon Linux bastion host that the CloudFormation stack created.
  3. Choose Connect.
  4. Copy the value for SSHCommand.
  5. On the SSH client, change the directory to the location where you saved the EC2 private key, and enter the SSHCommand value.
  6. On the console, open the AWS Secrets Manager dashboard.
  7. Choose the secret secretAuroraMasterUser-*.
  8. Choose Retrieve secret value.
  9. Record the password under Secret key/value, which you use to log in to the Aurora MySQL cluster.
  10. Choose the secret SecretRedshiftMasterUser.
  11. Choose Retrieve secret value.
  12. Record the password under Secret key/value, which you use to log in to the Amazon Redshift cluster.
  13. Log in to both Aurora MySQL using the MySQL Command-Line Client and Amazon Redshift using query editor.

The CloudFormation template has already set up MySQL Command-Line Client binaries on the Amazon Linux bastion host.

  1. On the Amazon Redshift console, choose Editor.
  2. Choose Query editor.
  3. For Connection, choose Create new connection.
  4. For Cluster, choose the Amazon Redshift cluster.
  5. For Database name, enter your database.
  6. Enter the database user and password recorded earlier.
  7. Choose Connect to database.

Choose Connect to database.

  1. Enter the following SQL command:
    select "table" from svv_table_info where schema='public';

You should see 25 tables as the output.

You should see 25 tables as the output.

  1. Launch a command prompt session of the bastion host and enter the following code (substitute <AuroraClusterEndpoint> with the value from the AWS CloudFormation output):
    mysql --host=<AuroraClusterEndpoint> --user=awsuser --password=<database user password recorded earlier>

  1. Enter the following SQL command:
    use tpc;
    show tables;
    

You should see the following eight tables as the output:

mysql> use tpc;
Reading table information for completion of table and column names
You can turn off this feature to get a quicker startup with -A

Database changed
mysql> show tables;
+------------------------+
| Tables_in_tpc          |
+------------------------+
| customer               |
| customer_address       |
| household_demographics |
| income_band            |
| item                   |
| promotion              |
| web_page               |
| web_sales              |
+------------------------+
8 rows in set (0.01 sec)

Completing federated query setup

The final step is to create an external schema to connect to the Aurora MySQL instance. The following example code creates an external schema statement that you need to run on your Amazon Redshift cluster to complete this step:

CREATE EXTERNAL SCHEMA IF NOT EXISTS mysqlfq 
FROM MYSQL 
DATABASE 'tpc' 
URI '<AuroraClusterEndpoint>' 
PORT 3306 
IAM_ROLE '<IAMRole>' 
SECRET_ARN '<SecretARN>'

Use the following parameters:

  • URI – The AuroraClusterEndpoint value from the CloudFormation stack outputs. The value is in the format <stackname>-cluster.<randomcharacter>.us-east-1.rds.amazonaws.com.
  • IAM_Role – The RedshiftClusterRoleArn value from the CloudFormation stack outputs. The value is in the format arn:aws:iam::<accountnumber>:role/<stackname>-RedshiftClusterRole-<randomcharacter>.
  • Secret_ARN – The AuroraSecretArn value from the CloudFormation stack outputs. The value is in the format arn:aws:secretsmanager:us-east-1:<accountnumber>: secret:secretAuroraMasterUser-<randomcharacter>. 

Federated query test

Now that you have set up federated query, you can start testing the feature using the TPC-DS dataset that was preloaded into both Aurora MySQL and Amazon Redshift.

For example, the following query aggregates the total net sales by product category and class from the web_sales fact table and date and item dimension tables. Tables web_sales and date are stored in Amazon Redshift, and the item table is stored in Aurora MySQL:

select
    sum(ws_net_paid
    ) as total_sum, i_category, i_class, 0 as g_category, 0 as g_class  
from
    web_sales ,date_dim d1 ,mysqlfq.item 
where
    d1.d_month_seq between 1205 
    and 1205+11 
    and d1.d_date_sk = ws_sold_date_sk 
    and i_item_sk = ws_item_sk 
group
    by i_category,i_class ; 

You can continue to experiment with the dataset and explore the three main use cases in the post [exact name of post title with embedded link].

Cleaning up

When you’re finished, delete the CloudFormation stack, because some of the AWS resources in this walkthrough incur a cost if you continue to use them. Complete the following steps:

  1. On the AWS CloudFormation console, choose Stacks.
  2. Choose the stack you launched in this walkthrough. The stack must be currently running.
  3. In the stack details pane, choose Delete.
  4. Choose Delete stack.

Summary

This post showed you how to automate the creation of an Aurora MySQL and Amazon Redshift cluster preloaded with the TPC-DS dataset, the prerequisites for the new Amazon Redshift federated query feature using AWS CloudFormation, and a single manual step to complete the setup. It also provided an example federated query using the TPC-DS dataset, which you can use to accelerate your learning and adoption of the new feature. You can continue to modify the CloudFormation templates from this post to support your business needs.

If you have any questions or suggestions, please leave a comment.


About the Authors

BP Yau is an Analytics Specialist Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.


Srikanth Sopirala is a Sr. Specialist Solutions Architect, Analytics at AWS. He is passionate about helping customers build scalable data and analytics solutions in the cloud.


Zhouyi Yang is a Software Development Engineer for Amazon Redshift Query Processing team. He’s passionate about gaining new knowledge about large databases and has worked on SQL language features such as federated query and IAM role privilege control. In his spare time, he enjoys swimming, tennis, and reading.


Entong Shen is a Senior Software Development Engineer for Amazon Redshift. He has been working on MPP databases for over 8 years and has focused on query optimization, statistics, and SQL language features such as stored procedures and federated query. In his spare time, he enjoys listening to music of all genres and working in his succulent garden.


New charts, formatting, and layout options in Amazon QuickSight

Post Syndicated from Sapna Maheshwari original https://aws.amazon.com/blogs/big-data/new-charts-formatting-and-layout-options-in-amazon-quicksight/

Amazon QuickSight is a fast, cloud-powered business intelligence (BI) service that makes it easy to create and deliver insights to everyone in your organization. In this post, we explore how authors of QuickSight dashboards can use some of the new chart types, layout options, and dashboard formatting controls to deliver dashboards that intuitively deliver insights to all your users, whether within QuickSight or embedded in your websites or multi-tenant apps.

This blog post explores some of the visualization and dashboard customization features offered in Amazon QuickSight with the following datasets:

Picking the right chart for your use case

In this section, we explore some of the new charts QuickSight introduced in 2020 and how these help with various use cases.

Funnel charts

Funnel charts help visualize the progressive reduction of data as it passes from one phase to another. Data in each of these phases is represented as different portions of 100% (the whole). The most common use of the funnel chart is in visualizing conversion data. For example, you can represent sales lead generation showing different stages of sales conversion from first contact to lead generation.

To build a funnel chart with our Ads dataset, complete the following steps:

  1. On the analysis page, choose Visualize.
  2. Choose Add, then choose Add visual.
  3. In the Visual types pane, choose the funnel chart icon.
  4. For Group by, choose Stage.
  5. For Value, choose Ad name.
  6. To change default configuration, choose the gear icon.
  7. In the Data labels section, for Metric label style, choose Value and percent of first.

The video below demonstrates these steps.

Stacked area charts

Stacked area charts are best used to visualize part-to-whole relationships, to show how each category contributes to the cumulative total. For this post, we create a stacked area chart with the Ads dataset.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual types pane, choose the stacked area chart icon.
  • For X axis, choose Date (MONTH).
  • For Value, choose Cost (Sum).
  • For Color, choose Segment.
  • Choose the gear icon.
  • Under Legend, deselect Legend title.
  • Under Y-Axis, select Show Y axis label.
  • Under Data labels, select Show data labels.
  • Choose your desired position, font size, font color, and label pattern.

Histograms

Histograms help visualize the frequency distribution of a dataset and display numerical data by grouping data into bins of equal width. Each bin is plotted as a bar whose height corresponds to the number of data points within the bin.

For this post, we use the Student Performance dataset to create a histogram.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual types pane, choose the histogram icon.
  • For Value, choose math score.

You can customize the histogram to show bins by bin count, bin width, or a custom start value. For this post, we sort by bin width.

  • Under Histogram, select Bin width.
  • For Bin width, enter 5.

Box plots

Box plot (also called box or whisker plot) is a standardized way of displaying distribution of data based on a five-number summary (minimum, first quartile (Q1), median, third quartile (Q3), and maximum). This is useful to determine if data is symmetrical, skewed, or tightly grouped. Box plots also show outliers.

For this post, we create a box plot on the Student Performance dataset.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual types pane, choose the box plot icon.
  • For Group by, choose Gender.
  • For Value, choose writing score and reading score.
  • In the visual settings, under Box plot, select Show outliers and Show all data points.
  • Under Legend, deselect Show legend title.


Waterfall charts

Waterfall charts help you understand the cumulative effect of sequentially introduced positive or negative values. This is great to understand contributions to a whole, for example the main contributors to a monthly increase in revenue, or the breakdown of revenue vs costs.

We use the P&L dataset to create a waterfall chart.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual selection pane, choose the waterfall chart icon.
  • For Category, choose Line item.
  • For Value¸ choose Value (Sum).
  • Under Legend, deselect Show legend title.
  • For Position, select Bottom.
  • Under Title, deselect Show title.

Choropleth maps

Choropleth maps use differences in shading or coloring within geographical areas or regions to indicate the value of a variable in those areas

We use the Patient Info dataset to create a choropleth map.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual types pane, choose the funnel chart icon.
  • For Location, choose State.
  • For Color, choose Revenue (Sum).
  • Choose the menu options icon (…) and choose Conditional formatting.
  • For Column, choose Revenue.
  • For Fill type, select Gradient.
  • For Max value, choose a color (for this post, we choose blue).

The video below demonstrates these steps.

You can also control the color and shading of the geographic areas using conditional formatting as shown below.

The video below demonstrates these steps.

Additionally, you can configure the alignment of column headers and content within. You can change the vertical alignment – top, middle, bottom and also the horizontal alignment – left, center and right.

Customization and formatting options

QuickSight also supports several formatting options that allow you to streamline visualizations and convey additional information in your dashboards.

Table/pivot table formatting

Pin or unpin and add custom text totals

You can now pin totals to the top or bottom of tables and pivot tables in QuickSight. This feature helps you view the totals even while scrolling through the tables.

  • Go to visual setting (gear icon on the visual menu).
  • Under Total, select Pin totals.
  • For Position, choose a position (for this post, we choose Bottom).

Additionally, you can edit the text you want to show on totals and subtotals.

  • For Total label, enter your custom text (for this post, we enter Grand Total).

Table alignment and wrapping

You can now align horizontal (left, right, center, auto) and vertical (top, middle, bottom) alignment on column headers and cell values in a table visual. Additionally, you can apply text wrapping on table and pivot table headers so that long headers are readable versus having to scroll over the header.

These options are available under Table options.

Hide +/- buttons on pivot tables

You can now show or hide +/- buttons on pivot tables. This allows you to improve presentation of pivot tables by removing these icons and keeping the pivot table simple. This option is available under Styling.

Visual customization options

In this section, we discuss additional customization options in QuickSight.

Custom sorting

If you want to sort your charts in a custom defined order different from the default alphabetic order, you can now do so on QuickSight. For example, you can sort geographical regions in the order of East, West, Central, and South, by ranking these regions 1– 4 and then sorting on this rank field. See video below to learn how to.

You can also therefore sort using any other critical metric fields that aren’t part of the visual. Choose your field well and choose Sort options to see available sort order options.

You can also therefore sort on any other critical metric fields that aren’t part of the visual. Choose your field well and choose Sort options to see available sort order options.

The following screenshot shows your sorted visualizations.


Adding descriptive text, images, and links

You can add images or logos to your dashboard using QuickSight’s narrative component available in Enterprise Edition.

  • On the analysis page, choose Visualize.
  • Choose Add, then choose Add visual.
  • In the Visual types pane, choose the insights icon.
  • Choose Customize insight.
  • Remove any existing text and add your custom text.

You can also add hyperlinks to text and images. Upload your image to a secure location where the image is accessible to QuickSight and your users.

The video below demonstrates these steps.

Customizing colors and fonts

QuickSight offers easy-to-build themes that allow customization of the color palette, background and foreground colors, spacing, fonts, and more. Themes can be created by authors and shared within an account, and are also accessible via APIs for programmatic management. Themes can also be defaulted for all users in the organization using APIs.

You can also prioritize the colors that you want to use in your dashboard by prioritizing them within your theme’s color palette.

You can apply predefined themes available out of the box or create your own themes that fit your corporate branding. The following screenshots show how a dashboard looks in both dark and light themes.

For more information, see Evolve your analytics with Amazon QuickSight’s new APIs and theming capabilities.

Null value customization

You may occasionally have null values in your data and want to represent nulls with different annotations. For each of the dimensions and metrics in the dataset, you can provide custom text for null values. Go to More formatting options for any field.

The option is available under Null values.

Reference lines

You can draw reference lines based on a calculated field or a constant value. Choose the gear icon and navigate to reference lines section. In the following screenshot, the orange reference line is based off a calculation (average profit) and the black reference line is plotted on a constant value of 1,000.

You can also link reference lines to parameters via a calculated field, which allows you to create what-if scenarios within your dashboard.

Custom colors on heat and tree maps

Color gradient customization on heat and tree maps allows you to select colors for lower, intermediate, and upper limits so that the gradient is applied within these colors. You can configure this under Color in the visual settings.

Using logarithmic scale

If your metric numbers aren’t in the same order of magnitude, where some are extremely on the higher end and others on the lower end (for example, representing stock price for different entities or pandemic spread rates), you can represent them on a logarithmic scale so they’re normalized, yet relative. To use logarithmic scale, go to visual setting and under Y-Axis, for Scale, select Logarithmic.

The following screenshot shows your visualization after applying logarithmic scale.

Adjustable font size

You can now apply different font sizes on all visual content and visuals titles. In pivot tables and tables, you can see font sizes for table headers, cells, totals, and subtotals. In key performance indicators (KPIs), you can set font sizes for primary and comparison values, which allows you to keep dashboards dense and add more KPIs.

Actions

Finally, to all these charts, you can apply the following actions:

  • Filter actions– Select points on a chart to filter across the dashboard. QuickSight supports hierarchical filter actions that allow you to trigger one filter action from more than one chart. For more information, see Enhancing dashboard interactivity with Amazon QuickSight Actions.
  • URL actions – Trigger navigation from the dashboard to an external website and pass dynamic values within a URL.

Layout enhancements

QuickSight dashboards default to auto-fit mode, which makes them responsive based on screen size. However, in many situations, it’s preferable that the view you design is exactly what end-users see, whether on a laptop or a large monitor. QuickSight offers optimized layouts that allow you to pick a specific screen resolution to optimize for (such as the screen size most of your users use on a daily basis), and QuickSight automatically scales the dashboard view to render appropriately on larger or smaller screens. This doesn’t affect mobile devices—QuickSight automatically optimizes for mobile devices using a single-column layout. To adjust the scaling mode, choose Settings in the navigation pane while in dashboard authoring (analysis) mode.

If you build your dashboard for a 1024 px screen, for example, QuickSight scales that view to a larger or smaller screen to ensure that all users see the same content (mobile devices continue to fall back to a single-column, mobile-specific layout to ensure usability). Opting for the optimized mode also makes sure that your email reports look exactly like the dashboard that your viewers interact with.

On-sheet filter controls

You can now add filters to your dashboard directly without having to create parameters. Choose the field that you need to filter on choose Add filter for this field. Choose the newly added filter and choose Add to sheet.

If you need to pin it to the controls section, choose the filter and choose Pin to top.

The video below demonstrates these steps.

Thus, QuickSight allows you to choose from any of these control types to add to dashboards – single-select drop-downs, multi-select drop-downs, date and time picker, single-sided slider, single-line text box, time range picker, relative date selection, and numeric range slider. Learn more about on-sheet controls from the blog post here.

Other launches in 2020

While this blog covers all key charting and visualization launches in 2020, you can take a look at all new features enabled across other areas within QuickSight from this blog post here.

Conclusion

With these new QuickSight feature releases, you can now choose the chart type that is best suited to represent your data. You can provide richer dashboards for your readers by using the new formatting table options, dynamic titles, and reference lines. For more information about authoring dashboards in QuickSight, watch the virtual workshop Build Advanced Analytics and Dashboards with Amazon QuickSight and consider subscribing to the Amazon QuickSight YouTube channel for the latest training and feature walkthroughs.


About the Author

Sapna Maheshwari is a Specialist Solutions Architect for Amazon QuickSight. She is passionate about telling stories with data. In her previous roles at American Express and Early Warning services , she managed and led several projects in the data and analytics space.She enjoys helping customers unearth actionable insights from their data.

Boosting your data lake insights using the Amazon Athena Query Federation SDK

Post Syndicated from Adir Sharabi original https://aws.amazon.com/blogs/big-data/boosting-your-data-lake-insights-using-the-amazon-athena-query-federation-sdk/

Today’s modern applications use multiple purpose-built database engines, including relational, key-value, document, and in-memory databases. This purpose-built approach improves the way applications use data by providing better performance and reducing cost. However, the approach raises some challenges for data teams that need to provide a holistic view on top of these database engines, and especially when they need to merge the data with datasets in the organization’s data lake.

In this post, we show how to use the Amazon Athena Query Federation SDK to easily enrich your data in Amazon Simple Storage Service (Amazon S3) with data from external datastores, apply complex transformations, and get predictive insights by inferencing machine learning (ML) models.

We start by running a query to enrich an S3 backed table that holds features extracted from breast cancer images with fictional patient personal information stored in Amazon DynamoDB. We then use the Athena UDF functionality to decrypt sensitive information stored in the table. Next, we select these features and use Athena integration with Amazon SageMaker to pass them to a linear learner model to predict whether breast cancer is present. Lastly, we show an Amazon QuickSight dashboard to visualize the results.

For this post, we use the following resources:

  • A dataset of features computed from a digitized image of a fine needle aspirate of a breast mass. Such features include radius, texture, perimeter, area, and smoothness. The dataset is stored as a CSV file in Amazon S3.
  • Patient’s personal information (such as age range, email, and country) stored in DynamoDB.
  • A linear learner model deployed into a SageMaker endpoint to predict breast cancer. For more information, see Call an Amazon SageMaker model endpoint using Amazon API Gateway and AWS Lambda.

Prerequisites

Athena Query Federation is now generally available in US East (Ohio), US East (N. Virginia), and US West (Oregon). To use this feature, upgrade your engine version to Athena engine version 2 in your workgroup settings. To enable this feature in other Regions, you need to create an Athena workgroup named AmazonAthenaPreviewFunctionality and join that workgroup. Workgroups allows us to:

  • Isolate users, teams, applications, or workloads into groups
  • Enforce costs constraints per query or workgroup
  • Track query-related metrics for all workgroup queries in Amazon CloudWatch

For more information, see Managing Workgroups.

Creating a DynamoDB table and SageMaker endpoint

For the post, we create a new DynamoDB table with synthetic patient data. For the inference requests, we create a new SageMaker endpoint.

  1. Deploy the following AWS CloudFormation stack in us-east-1:

The stack performs the following:

  • Creates a DynamoDB table
  • Creates and triggers an AWS Lambda function to load the table with data
  • Creates a SageMaker endpoint for inference requests

It can take up to 10 minutes for the CloudFormation stack to create the resources.

  1. After the resource creation is complete, navigate to the AWS CloudFormation console.
  2. Choose the boost-your-datalake-insights stack
  3. On the Outputs tab, copy the values for DynamoTableName and SMEndpointName. You use these values later in the post.

Downloading the dataset

Under new or existing bucket create a folder named breast_cancer_features. Download the breast_cancer_raw_data.csv file and upload it to breast_cancer_features folder in your bucket. This file contains the Breast Cancer Wisconsin (Diagnostic) Data Set, available at https://archive.ics.uci.edu/ml/datasets/Breast+Cancer+Wisconsin+%28Diagnostic%29.

The file holds 570 records with 30 columns of values computed for each cell nucleus. Such features include radius, texture, perimeter, area, smoothness, compactness, concavity, concave points, symmetry, and fractal dimension. The following screenshot displays a few records from the file.

Creating the features table in Athena

To query this dataset from Athena, you need to create an external table that points to that file. There are several ways to create table in Athena. For this post, we use a Hive data definition language (DDL) statement.

  1. On the Athena console, if using a non-GA Region, switch to the AmazonAthenaPreviewFunctionality workgroup created earlier.
  2. Enter the following statement:
    CREATE EXTERNAL TABLE breast_cancer_features(
    id string, radius_mean double, texture_mean double, perimeter_mean double, area_mean double, smoothness_mean double, compactness_mean double, concavity_mean double, concave_points_mean double, symmetry_mean double, fractal_dimension_mean double, radius_se double, texture_se double, perimeter_se double, area_se double, smoothness_se double, compactness_se double, concavity_se double, concave_points_se double, symmetry_se double, fractal_dimension_se double, radius_worst double, texture_worst double, perimeter_worst double, area_worst double, smoothness_worst double, compactness_worst double, concavity_worst double, concave_points_worst double, symmetry_worst double, fractal_dimension_worst double)
    ROW FORMAT DELIMITED 
      FIELDS TERMINATED BY ',' 
    STORED AS INPUTFORMAT 
      'org.apache.hadoop.mapred.TextInputFormat' 
    OUTPUTFORMAT 
      'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION
      's3://<bucket>/breast_cancer_features/'
    TBLPROPERTIES (
      'classification'='csv', 
      'columnsOrdered'='true', 
      'compressionType'='none', 
      'delimiter'=',', 
      'skip.header.line.count'='1')

  1. Choose Run Query or press CTRL + Enter.

After the table is created successfully, we can run queries such as the following, to profile your data and better understand how it’s distributed:

SELECT variance(radius_mean) AS variance,
        stddev(radius_mean) AS stddev ,
        min(radius_mean) AS min,
         max(radius_mean) AS max,
         avg(radius_mean) AS avg
FROM "default"."breast_cancer_features"

The following screenshot shows our results.

Joining the features table with data stored in DynamoDB

In this step, we enrich the features table by joining it with the personal information stored in DynamoDB. With Athena Query Federation, you can run SQL queries across data stored in relational, non-relational, object, and custom data sources.

The following screenshot displays a few records from the DynamoDB table.

To join the features table stored in Amazon S3 with the personal data stored in DynamoDB, we need to create a data source connector that runs on Lambda to run the federated query. A data source connector is a piece of code that can translate between your target data source and Athena. You can think of a connector as an extension of the query engine in Athena.

Prebuilt Athena data source connectors exist for data sources like Amazon CloudWatch Logs, DynamoDB, Amazon DocumentDB (with MongoDB capability), and Amazon Relational Database Service (Amazon RDS), and JDBC-compliant relational data sources such as MySQL and PostgreSQL. You can also use the Athena Query Federation SDK to write custom connectors.

Preparing to create federated queries is a two-part process: deploying a Lambda function data source connector, and connecting the Lambda function to a data source.

Deploying a Lambda function data source connector

To deploy the data source connector, complete the following steps

  1. On the Athena console, choose Data sources.
  2. Choose Connect data source.
  3. Choose Query a data source.
  4. For Choose a data source, choose the data source that you want to query with Athena, such as Amazon DynamoDB.
  5. Choose Next.
  6. For Lambda function, choose Configure new AWS Lambda function.

The function page for the connector that you chose opens on the Lambda console. The page includes detailed information about the connector.

  1. Under Application settings, specify the required information. At a minimum, this includes:
    • AthenaCatalogName – A name for the Lambda function that indicates the data source that it targets, such as athena_dynamodb_connector.
    • SpillBucket – An S3 bucket in your account to store data that exceeds Lambda function response size limits.

For more information about the remaining configurable options, see Available Connectors on GitHub.

  1. Select I acknowledge that this app creates custom IAM roles.
  2. Choose Deploy.

The Resources section on the Lambda console shows the deployment status of the connector and informs you when the deployment is complete.

Connecting to a data source

After you deploy the data source connector to your account, you can connect it to a data source from Athena.

  1. On the Athena console, choose Connect data source.
  2. Choose Query a data source.
  3. Choose the data source for the connector that you just deployed, such as Amazon DynamoDB. If you used the Athena Query Federation SDK to create your own connector and have deployed it to your account, choose All other data sources.
  4. Choose Next.
  5. For Choose Lambda function, choose the function that you named previously (athena_dynamodb_connector).
  6. For Catalog name, enter a unique name to use for the data source in your SQL queries, such as dynamo_db.

The name can be up to 127 characters and must be unique within your account. It can’t be changed after creation. Valid characters are a–z, A–Z, 0–9, _, @, and -. The names awsdatacatalog, hive, jmx, and system are reserved by Athena and can’t be used for custom catalog names.

  1. Choose Connect.

The Data sources page shows your connector in the list of catalog names. You can now use the connector in your queries.

Querying the external data source

To query your external data source, complete the following steps:

  1. In the Athena Query editor, for Data source, choose dynamo_db.

The DynamoDB table appears in the Tables list.

  1. Choose (three dots) and choose Preview table.

Now we can run queries like the following to enrich and get more insights on our data by joining it with additional data that was stored in DynamoDB:

SELECT age, count(*)
FROM breast_cancer_features d
JOIN "dynamo_db"."default"."<DynamoTableName>" p
ON d.id = p.patient_id
GROUP BY age

The following screenshot shows our results.

Using custom UDFs to decrypt the patient’s email

When looking at our patient’s personal information stored in the DynamoDB table, we can see that the patient’s email is encrypted. We want to allow our users to get the decrypted email while querying with Athena without needing to run custom ETL, which requires us to store it decrypted.

User Defined Functions (UDFs) in Athena allow you to create custom functions to process records or groups of records. A UDF accepts parameters, performs the work, and returns a result. However, UDFs in Athena have the following limitations:

  • Scalar UDFs only – Athena only supports scalar UDFs, which process one row at a time and return a single column value. Athena passes a batch of rows to the UDF each time it invokes a Lambda function.
  • Java runtime only – As of this writing, Athena UDFs support only the Java 8 runtime for Lambda.

To use this feature in preview, you must create an Athena workgroup named AmazonAthenaPreviewFunctionality and join that workgroup, as specified in prerequisites section. For more information, see Querying with User Defined Functions.

Deploying a custom UDF

In this post, we use the decrypt method from the example UDF we published. The same encryption key that we used for the encryption should also be used for the decryption. We store that string in AWS Secrets Manager and use the Athena Query Federation SDKs to retrieve the stored key when the function is called.

  1. On the Secrets Manager console, choose Store a new secret.
  2. For Select secret type, select Other type of secrets.
  3. Choose Plaintext.
  4. Remove all the JSON brackets and enter a base64 encoded string as data key, such as AQIDBAUGBwgJAAECAwQFBg==
  5. For Select the encryption key, choose DefaultEncryptionKey.
  6. Choose Next.

  1. Enter athena_encrypt_udf_key as the secret name.
  2. Choose Next.
  3. Chose Next again.
  4. Chose Store.

Next, we deploy the Lambda function that runs the UDF.

  1. On the AWS Serverless Application Repository console, in the navigation pane, choose Available applications.
  2. Select Show apps that create custom IAM roles or resource policies.
  3. In the search box, enter AthenaUserDefinedFunctions.
  4. Choose the application from the result pane.

The Lambda function’s Application details page opens on the Lambda console.

  1. For SecretNameOrPrefix, enter the name or prefix of a set of names within Secrets Manager that this function should have access to, such as athena_encrypt_udf_key* (make sure to include an asterisk at the end).
  2. For LambdaFunctionName, enter the name of the Lambda function that runs your UDFs, such as athena_udf.
  3. Select I acknowledge that this app creates custom IAM roles.
  4. Choose Deploy.

The Resources section of the Lambda console shows the deployment status of the connector and informs you when the deployment is complete.

Querying with UDFs

The USING FUNCTION clause specifies a UDF or multiple UDFs that can be referenced by a subsequent SELECT statement in the query. You need the method name for the UDF and the name of the Lambda function that hosts the UDF.

In our example, the decrypt method gets two parameters: encrypted_col and secretName. We define the function and run the following query:

USING FUNCTION decrypt(encrypted_col VARCHAR, secretName VARCHAR)
RETURNS VARCHAR
TYPE LAMBDA_INVOKE WITH (lambda_name ='athena_udf')

SELECT encrypted_email, 
    decrypt(encrypted_email,'athena_encrypt_udf_key') AS decrypted_email
FROM "dynamo_db"."default"."<DynamoTableName>"

The following screenshot shows the query results.

Using Athena ML to predict breast cancer

To get predictive insights from our data using ML models, we need to write a code to enable inference against a deployed model. Data analysts are often skilled in using SQL, but may not have expertise in programming. ML with Athena bridges this gap and lets you run inference on models deployed on SageMaker by writing SQL statements in Athena. This feature simplifies access for data analysis to ML models such as anomaly detection, customer cohort analysis, and sales predictions, and improves productivity. This eliminates the need to use complex programming methods or offload data and jobs orchestration to run inference. 

SageMaker is a fully managed ML service, where data scientists and developers can quickly and easily build and train ML models. In addition, SageMaker allows you to deploy your model to get predictions in one of two ways:

Running a SQL statement with SageMaker inference to predict breast cancer

To perform inference from Athena, you need to train the model based on historical labeled data and deploy it into the SageMaker hosting service. In this post, we use a linear learner model to predict breast cancer out of features we used before. The model was already deployed as part of the CloudFormation stack as you can see in the screenshot below from the SageMaker console.

To use ML with Athena, you define a function with the USING FUNCTION clause. The function points to the SageMaker model endpoint that you want to use and specifies the variable names and data types to pass to the model. Subsequent clauses in the query reference the function to pass values to the model. The model runs inference based on the values that the query passes and then returns inference results.

In our example, the model endpoint is SMEndpoint-odPIqmf9LjUh and the variables are the feature columns from the breast_cancer_features table. We define the function and run the following query:

USING FUNCTION predict_breast_cancer(radius_mean double, texture_mean double, perimeter_mean double, area_mean double, smoothness_mean double, compactness_mean double, concavity_mean double, concave_points_mean double, symmetry_mean double, fractal_dimension_mean double, radius_se double, texture_se double, perimeter_se double, area_se double, smoothness_se double, compactness_se double, concavity_se double, concave_points_se double, symmetry_se double, fractal_dimension_se double, radius_worst double, texture_worst double, perimeter_worst double, area_worst double, smoothness_worst double, compactness_worst double, concavity_worst double, concave_points_worst double, symmetry_worst double, fractal_dimension_worst double) 
RETURNS DOUBLE 
TYPE SAGEMAKER_INVOKE_ENDPOINT WITH (sagemaker_endpoint = '<SMEndpointName>')

SELECT id, prediction, CASE WHEN round(prediction)=1 THEN 'B' ELSE 'M' END AS diagnosis
FROM( SELECT id, predict_breast_cancer(radius_mean, texture_mean, perimeter_mean, area_mean, smoothness_mean, compactness_mean, concavity_mean, concave_points_mean, symmetry_mean, fractal_dimension_mean, radius_se, texture_se, perimeter_se, area_se, smoothness_se, compactness_se, concavity_se, concave_points_se, symmetry_se, fractal_dimension_se, radius_worst, texture_worst, perimeter_worst, area_worst, smoothness_worst, compactness_worst, concavity_worst, concave_points_worst, symmetry_worst, fractal_dimension_worst) AS prediction FROM breast_cancer_features)a

In the following query results, you can see the prediction column returned by the model. The diagnosis column that derives from it is either B for benign or M for malignant.

Visualizing the data using QuickSight

Because many decision-makers aren’t familiar with SQL syntax, they want to consume the data in more graphic way, such as through charts and dashboards. Visualizing the data is also required by data scientists to identify trends and anomalies, and understand how our data behaves.

Before we visualize our data with QuickSight, in order to get the best performances, we create a new dataset in Amazon S3 that holds all the patient’s personal information joined with the breast cancer diagnostic we got from the ML model inference. We use Athena’s CREATE TABLE AS SELECT (CTAS) statement to create the table and populate it with the joint data:

CREATE TABLE breast_cancer_final
WITH (
format = 'PARQUET',
parquet_compression = 'SNAPPY',
external_location = 's3://<bucket>/breast_cancer_final/')
AS
USING FUNCTION predict_breast_cancer(radius_mean double, texture_mean double, perimeter_mean double, area_mean double, smoothness_mean double, compactness_mean double, concavity_mean double, concave_points_mean double, symmetry_mean double, fractal_dimension_mean double, radius_se double, texture_se double, perimeter_se double, area_se double, smoothness_se double, compactness_se double, concavity_se double, concave_points_se double, symmetry_se double, fractal_dimension_se double, radius_worst double, texture_worst double, perimeter_worst double, area_worst double, smoothness_worst double, compactness_worst double, concavity_worst double, concave_points_worst double, symmetry_worst double, fractal_dimension_worst double) 
RETURNS DOUBLE 
TYPE SAGEMAKER_INVOKE_ENDPOINT WITH (sagemaker_endpoint = '<SMEndpointName>')

SELECT *, CASE WHEN round(prediction)=1 THEN 'B' ELSE 'M' END AS diagnosis
FROM( SELECT id, p.*, predict_breast_cancer(radius_mean, texture_mean, perimeter_mean, area_mean, smoothness_mean, compactness_mean, concavity_mean, concave_points_mean, symmetry_mean, fractal_dimension_mean, radius_se, texture_se, perimeter_se, area_se, smoothness_se, compactness_se, concavity_se, concave_points_se, symmetry_se, fractal_dimension_se, radius_worst, texture_worst, perimeter_worst, area_worst, smoothness_worst, compactness_worst, concavity_worst, concave_points_worst, symmetry_worst, fractal_dimension_worst) AS prediction FROM breast_cancer_features d JOIN "dynamo_db"."default"."<DynamoTableName>" p
ON d.id = p.patient_id)a

When the query successfully finishes, we can start building our dashboards using QuickSight.

First, we create a dataset in QuickSight for our table in Athena. For instructions, see Creating a Dataset Using Amazon Athena Data.

Next, we create QuickSight visuals.

The following dashboard shows the distribution of age range using a pie visual, a patient count by diagnostic per week, the top five countries, and patient distribution over time with forecast enabled.

Clean up

Now to the final step, cleaning up the resources.

To avoid unnecessary charges on your AWS account, do the following:

  1. Destroy all of the resources created by the CloudFormation stack in create a DynamoDB table and SageMaker endpoint set up by deleting the stack after you’re done experimenting with it. You can follow the steps here to delete the stack.
  2. You have to manually delete the S3 bucket you created with the data uploaded and generated with Athena.

Conclusions

This post demonstrated how the Athena Query Federation SDK allows you to implement serverless ETL to get more out of your data in your Amazon S3 data lake. We showed how simple Athena SQL syntax allows you to enrich your data with an external datastore, perform business logic using custom UDFs, and get insights by running ML inference. We also visualized our enriched dataset by creating a dashboard in QuickSight.

If you have feedback about this post, please share it in the comments. If you have questions about implementing the solution used in this post, comment or open a thread on the Developer Tools forum.


About the Authors

Adir Sharabi is a Solutions Architect with Amazon Web Services. He works with AWS customers to help them architect secure, resilient, scalable and high performance applications in the cloud. He is also passionate about Data and helping customers to get the most out of it.


Eitan Sela is a Solutions Architect with Amazon Web Services. He works with AWS customers to provide guidance and technical assistance, helping them improve the value of their solutions when using AWS. Eitan also helps customers build and operate machine learning solutions on AWS. In his spare time, Eitan enjoys jogging and reading the latest machine learning articles.

Announcing Amazon Redshift federated querying to Amazon Aurora MySQL and Amazon RDS for MySQL

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/announcing-amazon-redshift-federated-querying-to-amazon-aurora-mysql-and-amazon-rds-for-mysql/

Since we launched Amazon Redshift as a cloud data warehouse service more than seven years ago, tens of thousands of customers have built analytics workloads using it. We’re always listening to your feedback and, in April 2020, we announced general availability for federated querying to Amazon Aurora PostgreSQL and Amazon Relational Database Service (Amazon RDS) for PostgreSQL to enable you to query data across your operational databases, your data warehouse, and your data lake to gain faster and deeper insights not possible otherwise.

Today, we’re launching a new feature of Amazon Redshift federated query to Amazon Aurora MySQL and Amazon RDS for MySQL to help you expand your operational databases in the MySQL family. With this lake house architecture expansion to support more operational data stores, you can query and combine data more easily in real time and store data in open file formats in your Amazon Simple Storage Service (Amazon S3) data lake. Your data can then be more available to other analytics and machine learning (ML) tools, rather than siloed in disparate data stores.

In this post, we share information about how to get started with this new federated query feature to MySQL.

Prerequisites

To try this new feature, create a new Amazon Redshift cluster in a sql_preview maintenance track and Aurora MySQL instance and load sample TPC data into both data stores. To make sure both Aurora MySQL DB instances can accept connections from the Amazon Redshift cluster, you should make sure that both your Amazon Redshift cluster and Aurora MySQL instances are in the same Amazon Virtual Private Cloud (Amazon VPC) and subnet group. This way, you can add the security group for the Amazon Redshift cluster to the inbound rules of the security group for the Aurora MySQL DB instance.

If your Amazon Redshift cluster and Aurora MySQL instances are in the different VPC, you can set up VPC peering or other networking to allow Amazon Redshift to make connections to your Aurora MySQL instances. For more information about VPC networking, see Working with a DB instance in a VPC.

Configuring AWS Secrets Manager for remote database credentials

Amazon Redshift needs database credentials to issue a federated query to a MySQL database. AWS Secrets Manager provides a centralized service to manage secrets and can be used to store your MySQL database credentials. Because Amazon Redshift retrieves and uses these credentials, they are transient, not stored in any generated code, and discarded after the query runs.

Storing credentials in Secrets Manager takes only a few minutes. To store a new secret, complete the following steps:

  1. On the Secrets Manager console, choose Secrets.
  2. Choose Store a new secret.
  3. For Select secret type, select Credentials for RDS database.
  4. For User name, enter a name.
  5. For Password, enter a password.
  6. For Select the encryption key, choose DefaultEncryptionkey.
  7. For Select which RDS database this secret will access, choose your database.

Storing credentials in Secrets Manager takes only a few minutes.

  1. Optionally, copy programmatic code for accessing your secret using your preferred programming languages (which is not needed for this post).
  2. Choose Next.

After you create the secret, you can retrieve the secret ARN by choosing the secret on the Secrets Manager console. The secret ARN is needed in the subsequent step.

After you create the secret, you can retrieve the secret ARN by choosing the secret on the Secrets Manager console.

Setting up IAM role

You can now pull everything together by embedding the secret ARN into an AWS Identity and Access Management (IAM) policy, naming the policy, and attaching it to an IAM role. See the following code:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AccessSecret",
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetResourcePolicy",
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret",
                "secretsmanager:ListSecretVersionIds"
            ],
            "Resource": "<SecretARN>"
        },
        {
            "Sid": "VisualEditor1",
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetRandomPassword",
                "secretsmanager:ListSecrets"
            ],
            "Resource": "*"
        }
    ]
}

Finally, attach the same IAM role to your Amazon Redshift cluster.

  1. On the Amazon Redshift console, choose Clusters.
  2. Choose your cluster.
  3. On the Actions drop-down menu, choose Manage IAM roles.

Finally, attach the same IAM role to your Amazon Redshift cluster.

  1. Choose and add the IAM role you just created.

Setting up external schema

The final step is to create an external schema to connect to your Aurora MySQL instance. The following example code creates the external schema statement that you need to run on your Amazon Redshift cluster to complete this step:

CREATE EXTERNAL SCHEMA IF NOT EXISTS mysqlfq 
FROM MYSQL 
DATABASE 'tpc' 
URI '<AuroraClusterEndpoint>' 
PORT 3306 
IAM_ROLE '<IAMRole>' 
SECRET_ARN '<SecretARN>'

Use the following parameters:

  • URI – Aurora MySQL cluster endpoint
  • IAM_Role – IAM role created from the previous step
  • Secret_ARN – Secret ARN

After you set up the external schema, you’re ready to run some queries to test different use cases.

Querying live operational data

You can now query real-time operational data in your Aurora MySQL instance from Amazon Redshift. Note that isolation level is read committed for MySQL. See the following code:

dev=# select top 10 ws_order_number from mysqlfq.web_sales;
 ws_order_number 
-----------------
        93628990
       157020207
         4338647
        41395871
        58468186
       171095867
        12514566
        74946143
         3418243
        67054239
(10 rows)

Querying mysqlfq.web_sales in Amazon Redshift routes the request to MySQL tpc database and web_sales table. If you examine the query plan, you can see the query runs at the MySQL instance as shown by the step Remote MySQL Seq Scan:

dev=# explain select top 10 ws_order_number from mysqlfq.web_sales;
                                          QUERY PLAN                                           
-----------------------------------------------------------------------------------------------
 XN Limit  (cost=0.00..0.20 rows=10 width=8)
   ->  XN MySQL Query Scan web_sales  (cost=0.00..6869.28 rows=343464 width=8)
         ->  Remote MySQL Seq Scan mysqlfq.web_sales  (cost=0.00..3434.64 rows=343464 width=8)
(3 rows)

Simplifying ELT and ETL

You can also extract operational data directly from your Aurora MySQL instance and load it into Amazon Redshift. See the following code:

dev=# create table staging_customer as select c_customer_id from mysqlfq.customer where c_customer_id not in (select c_customer_id from customer);
SELECT
dev=# select count(*) from staging_customer;
 count  
--------
 350000
(1 row)

The preceding code uses CTAS to create and load incremental data from your operational MySQL instance into a staging table in Amazon Redshift. You can then perform transformation and merge operations from the staging table to the target table. For more information, see Updating and inserting new data.

Combining operational data with data from your data warehouse and data lake

You can combine live operational data from your Aurora MySQL instance with data from your Amazon Redshift data warehouse and S3 data lake by creating a late binding view.

To access your S3 data lake historical data via Amazon Redshift Spectrum, create an external table:

create external schema mysqlspectrum
from data catalog
database 'spectrumdb'
iam_role '<IAMRole>'
create external database if not exists;
 
create external table mysqlspectrum.customer 
stored as parquet 
location 's3://<yourS3bucket>/customer/'
as select * from customer where c_customer_sk <= 100000;

You can then run queries on the view to gain insight on data across the three sources:

drop view vwCustomer;
create view vwCustomer as
select c_customer_sk, 'redshift' as source from public.customer where c_customer_sk > 100000
union all
select c_customer_sk, 'mysql' as source from mysqlfq.customer
union all
select c_customer_sk, 's3' as source from mysqlspectrum.customer
with no schema binding;

select * from vwCustomer where c_customer_sk in (1, 149712,29033279);

You should the following three records as output:

dev=# select * from vwCustomer where c_customer_sk in (1, 149712,29033279);
 c_customer_sk |  source  
---------------+----------
      29033279 | mysql
             1 | s3
        149712 | redshift
(3 rows)

If you examine the query plan, you can see that the predicates are pushed down to your MySQL instance to run:

dev=# explain select * from vwCustomer where c_customer_sk in (1,149712,29033279);
                                                                            QUERY PLAN                                                                            
------------------------------------------------------------------------------------------------------------------------------------------------------------------
 XN Subquery Scan vwcustomer  (cost=0.00..48398.40 rows=6988 width=36)
   ->  XN Append  (cost=0.00..48328.52 rows=6988 width=4)
         ->  XN Subquery Scan "*SELECT* 1"  (cost=0.00..40000.03 rows=3 width=4)
               ->  XN Seq Scan on customer  (cost=0.00..40000.00 rows=3 width=4)
                     Filter: (((c_customer_sk = 1) OR (c_customer_sk = 149712) OR (c_customer_sk = 29033279)) AND (c_customer_sk > 100000))
         ->  XN Subquery Scan "*SELECT* 2"  (cost=0.00..6548.63 rows=5492 width=4)
               ->  XN MySQL Query Scan customer  (cost=0.00..6493.71 rows=5492 width=4)
                     ->  Remote MySQL Seq Scan mysqlfq.customer  (cost=0.00..6438.79 rows=5492 width=4)
                           Filter: ((c_customer_sk = 1) OR (c_customer_sk = 149712) OR (c_customer_sk = 29033279))
         ->  XN Subquery Scan "*SELECT* 3"  (cost=0.00..1779.86 rows=1493 width=4)
               ->  XN S3 Query Scan customer  (cost=0.00..1764.93 rows=1493 width=4)
                     ->  S3 Seq Scan mysqlspectrum.customer location:"s3://<yourS3bucket>/customer" format:PARQUET  (cost=0.00..1750.00 rows=1493 width=4)
                           Filter: ((c_customer_sk = 1) OR (c_customer_sk = 149712) OR (c_customer_sk = 29033279))
(13 rows)

Available Now

Amazon Redshift federated querying to Aurora MySQL and Amazon RDS for MySQL is now available for public preview with Amazon Redshift release version 1.0.21591 or later. Refer to the AWS Region Table for Amazon Redshift availability and to check the version of your clusters.


About the Authors

BP Yau is an Analytics Specialist Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next-generation big data analytics platform using AWS technologies.


Zhouyi Yang is a Software Development Engineer for the Amazon Redshift Query Processing team. He’s passionate about gaining new knowledge about large databases and has worked on SQL language features such as federated query and IAM role privilege control. In his spare time, he enjoys swimming, tennis, and reading.


Entong Shen is a Senior Software Development Engineer for Amazon Redshift. He has been working on MPP databases for over 8 years and has focused on query optimization, statistics, and SQL language features such as stored procedures and federated query. In his spare time, he enjoys listening to music of all genres and working in his succulent garden.

Building high-quality benchmark tests for Amazon Redshift using SQLWorkbench and psql

Post Syndicated from Asser Moustafa original https://aws.amazon.com/blogs/big-data/building-high-quality-benchmark-tests-for-amazon-redshift-using-sqlworkbench-and-psql/

In the introductory post of this series, we discussed benchmarking benefits and best practices common across different open-source benchmarking tools. In this post, we discuss benchmarking Amazon Redshift with the SQLWorkbench and psql open-source tools. Let’s first start with a quick review of the introductory installment.

When you use Amazon Redshift to scale compute and storage independently, a need arises to profile the compute requirements of various production workloads so that your Amazon Redshift cluster configuration reflects an appropriately balanced compute layer. You also need an approach to scale up with eyes wide open, and benchmarking different Amazon Redshift cluster configurations against various production workloads can help you appropriately accommodate workload expansion. In addition, you may also use benchmark tests to proactively monitor a production cluster’s performance in real time.

For prospective Amazon Redshift customers, benchmarking Amazon Redshift is often one of the main components of their evaluation and a key source of insight into the price-to-performance ratio of different Amazon Redshift configurations.

Open-source tools, with their cost-efficiency and vendor neutrality, are often the preferred choice for profiling production workloads and benchmark tests. However, best practices for using these tools are scarce, possibly resulting in flawed compute profiles, flawed benchmark results, customer frustration, and bloated timelines.

One final point before we get started: there is a lot that could be said about benchmarking—more than can be accommodated in a single post. Analytics Specialists Solutions Architects such as myself frequently and happily engage with current and prospective customers to help you evaluate your benchmarking strategy and approach at no charge. I highly recommend you take advantage of that benefit by reaching out to your AWS account Solutions Architect.

SQLWorkbench

SQLWorkbench, also referred to as SQLWorkbench/J, is an open-source SQL query tool that you can freely download as a .zip file. It’s written in Java so it runs on Windows, Linux/UNIX, and macOS, and naturally requires a supported Java runtime environment (JRE). SQLWorkbench also requires a JDBC driver for the database (to download the latest Amazon Redshift JDBC driver, see Configuring a JDBC driver version 1.0 connection).

SQLWorkbench can run in GUI or console mode. I discuss both in this section, but in my experience, customers typically default to the GUI mode, so we explore that version first. Also, I have found that customers that use SQLWorkbench often use it in a Windows environment (something to keep in mind if operating system has a determination on which open-source tool you use).

Typically, you stand up a Windows EC2 instance to serve as your benchmark host, and install SQLWorkbench on that machine. When you have SQLWorkbench running, setting up a connection to your Amazon Redshift cluster is quite easy. For this post, I assume you’re familiar with the basics of JDBC connections. The following screenshot shows what the SQLWorkbench connection dialog box might look like when populated with connection information.

After establishing a successful connection to your Amazon Redshift cluster, a query tab opens, in which you can write and run SQL queries similar to that shown in the following screenshot.

For benchmark tests, it’s highly recommended to set the maxrows field to a relatively low number to avoid noise from long transmission times of large result sets.

Unlike the LIMIT clause in a SQL SELECT statement, which can alter (short-circuit) Amazon Redshift query processing, setting the maxrows field (whether to a value as low as 1 or something much higher) has no impact on query processing in Amazon Redshift; maxrows only impacts SQLWorkbench’s rendering workload and overhead. You can easily verify this by running the same query multiple times with different maxrows settings and observing that the number of rows returned for each query on the Amazon Redshift console query history page doesn’t change. Although the resulting query times should still be considered as query runtimes, they certainly help you get closer to a query’s execution time. Setting the maxrows field to a relatively low number also reduces the risk of SQLWorkbench running into an out-of-memory error from very large result sets.

This straightforward GUI interface is appealing because it has a minimal learning curve and quickly enables you to start submitting benchmark tests against your Amazon Redshift cluster. SQLWorkbench is a very useful tool, and it may be a good fit for informal or simple benchmark tests that deal with a handful of benchmark queries, relatively small tables (such as under 50 million rows in a fact table), and are focused more on determining general directionality of query runtimes (for example, cluster A was faster than cluster B at running business query 123), rather than capturing accurate query runtimes. The GUI interface can also be helpful for quickly and easily tweaking test queries to be more or less intense, or to correct SQL syntax if the query originated from a different platform.

However, for more formal and complex benchmark tests that deal with large tables and must capture accurate query runtimes, SQLWorkbench’s straightforward GUI interface faces a scalability challenge: inputting potentially hundreds or thousands of benchmark queries, running them sequentially or simultaneously, and capturing their runtimes in a practical manner can prove to be a huge challenge.

In addition, SQLWorkBench’s rendering and processing times for query result sets are added to a query’s runtime, and so even moderately sized query result sets can lead to potentially significant noise in query runtimes. For example, I recently observed a customer reduce their query runtimes by several orders of magnitude by switching to a command line tool while keeping all other aspects of their benchmark tests and environment constant. Some of the queries were straightforward filter queries with no joins, returning 400,000 rows from a 2 billion-row fact table with approximately 30 mostly integer columns.

Using console mode

One way to minimize the scale problem and rendering noise is to switch to SQLWorkbench console mode (the command line interface), which comes bundled with the GUI version of SQLWorkbench in the same downloadable .zip file.

In this section, we show one way to enter console mode from the Windows command line prompt (note the -showTiming=true flag that enables query execution times print on the screen) and connect to an Amazon Redshift cluster.

The following code starts SQLWorkbench in console mode:

c:\ sqlwbconsole64.exe -showTiming=true

When you’re in console mode, use the following command to connect to an Amazon Redshift cluster:

SQL> WbConnect -username=<Redshift User> -password=<Redshift User Password> -url=<fully qualified Redshift JDBC URL with port and database> -driver=<Redshift JDBC driver class name>
For example:
SQL> WbConnect -username=demouser -password=******* -url=jdbc:redshift://demo-poc-redshift-cluster.xxxxxx.us-west-2.redshift.amazonaws.com:8192/dev -driver=com.amazon.redshift.jdbc.Driver

The following screenshot shows our output.

Again, it’s recommended to set the maximum rows for the results sets to a relatively low number, using the following command:

SQL> set maxrows <number>;

Although console mode may have a slightly higher learning curve, it can significantly reduce potential rendering noise in a query’s runtime. In addition, SQLWorkbench’s console mode lends itself to scripting, which opens the door to many more sophisticated benchmarking scenarios, particularly when simulating concurrent users and capturing sophisticated metrics.

Comparing performance of SQLWorkbench modes

Let’s use an example use case to demonstrate the potential performance differences of both modes of SQLWorkbench. Although Example Corp is a hypothetical company, the use case is quite typical and realistic, and the benchmark results presented are based on actual customer experiences.

Example Corp has onboarded terabytes of data, over 100 ETL jobs, and thousands of business users to our Amazon Redshift deployment over the past quarter. Data architects and engineers have observed the Amazon Redshift cluster’s average CPU utilization steadily increase, and now wish to scale up the cluster before onboarding additional data, ETL jobs, and users waiting in the project pipeline.

To determine the optimal cluster size, we perform a few simple benchmark tests on different cluster configurations. We first identify five or so sufficiently complex production queries for benchmarking clusters of different sizes and instance types. We decide query runtime is a sufficient measure of the optimal cluster size, because we’re mainly interested in directional guidance (for example, query runtimes improved significantly with 1.5x cluster size, but only marginally with larger than 1.5x cluster sizes).

We can use an Amazon Redshift snapshot from our production cluster to quickly stand up a few differently configured clusters varying in node size or node type (such as ra3.4xl vs. ra3.16xl). We use a production snapshot to create the benchmark clusters so we can keep the cluster data identical.

However, manually running the benchmark queries individually using the SQLWorkbench GUI shows query runtimes actually increased in most cases (compared to the original production cluster) despite the more powerful clusters! Upon a closer look, we realize internet transport noise has not been isolated from the query runtimes. We stand up a dedicated test EC2 machine in the same VPC and Availability Zone as our benchmark Amazon Redshift clusters and install a SQLWorkbench GUI client.

Running the benchmark queries using the SQLWorkbench GUI provides similar query runtimes as the original cluster configuration. Again, not what was expected. Upon switching to SQLWorkbench console mode, however, we observe an improvement in query runtimes by several orders of magnitude.

psql

In my experience, psql is the preferred open-source command line query tool for customers running in a Linux/UNIX environment, so in this post, I assume a Linux EC2 instance is being used to run psql. If the standard Amazon Linux AMI was chosen (usually the first one in the list) during EC2 creation, you can use the following commands to update and verify psql v9.2 on the Linux EC2 instance:

> sudo yum update
> sudo yum install postgresql
> psql --help

Feel free to also search the freely available community AMIs, which might have newer versions of PostGreSQL server and the psql client pre-installed.

After psql is installed, connecting to an Amazon Redshift cluster is pretty straightforward by specifying a few command line parameters:

psql -h <Redshift JDBC endpoint> -p <Redshift port> -U <Redshift user> -d <Redshift database> 

The standard Amazon Redshift port is 5439, but I use port 8192 in the following code because of certain firewall requirements in my environment:

psql -h benchmark-redshift-cluster1.xxxxx.us-west-2.redshift.amazonaws.com -p 5439 -U masteruser -d dev

The following screenshot shows our output.

After you connect to the Amazon Redshift cluster, be sure to run the \timing on command to enable query timing.

It’s also highly recommended that you consider setting the FETCH_COUNT variable to a relatively low number on the psql console to avoid long transmission times for large result sets:

\set FETCH_COUNT 500 

By setting this variable, database cursors and the FETCH command are used in conjunction with queries. Setting this variable has no impact on query processing in Amazon Redshift, but rather the number of rows returned to the client application from the fully materialized result set.

Although the command line nature of psql may have a slightly higher learning curve than similar GUI applications, it also helps keep it lightweight and introduces minimal processing noise into a query’s runtime. For example, I observed a customer’s query runtime improve by several orders of magnitude by simply switching from a GUI tool to command line psql, while keeping all other aspects of the benchmark test and environment constant.

In addition, psql’s command line interface lends itself to scripting, which opens the door to many more sophisticated benchmarking scenarios, particularly when simulating concurrent users and capturing sophisticated concurrency metrics. In fact, a number of customizable, parameter-driven scripts have already been written by AWS Analytics Specialists such as myself for sophisticated benchmarking compute and concurrency scenarios, and are freely available to current and prospective customers.

Another utility that you can use in combination with such scripts is Simple Replay, a utility that is freely available on the Amazon Redshift Utilities GitHub repo. Simply Replay can extract workload histories from a source Amazon Redshift cluster and replay those workloads (using the psql command line client) with high fidelity on a different (such as a benchmark test) Amazon Redshift cluster.

For Simple Replay to extract workload details from an Amazon Redshift cluster, audit logging must be enabled in the cluster, and it may take about an hour for the most recent workloads to propagate to the audit logs.

After we run the extract command, Simple Replay extracts workload information such as the connection patterns (for example, number of users and their connection timing), COPY and UNLOAD commands, and other SQL queries so that they can be replayed on a different Amazon Redshift cluster with high fidelity (and, in our case, using psql command line as the SQL client). The following screenshot shows our output.

The workload details are typically stored in an Amazon Simple Storage Service (Amazon S3) bucket, which is specified in the Simple Replay configuration file, among other properties. See the following screenshot.

After running the python3 Extraction.py extraction.yaml command on the command line, we can review the workload details in our target S3 bucket to verify that the expected complexity was captured. The following screenshot shows the workload details on the Amazon S3 console.

The next step is to replay the extracted workload on a baseline cluster that mirrors our production cluster configuration (to establish a baseline runtime profile) and one or more target clusters using Simple Replay’s replay capability, as shown in the following screenshot.

Now let’s take another look at the example scenario presented in the previous section to demonstrate using the psql command line client with Simple Replay. Again, Example Corp has onboarded terabytes of data, over 100 ETL jobs, and thousands of business users to our Amazon Redshift deployment over the past quarter. Data architects and engineers have observed the Amazon Redshift cluster’s average CPU utilization steadily increase, and now wish to scale the cluster up (again) before onboarding additional data, ETL jobs, and users waiting in the project pipeline.

To determine the optimal cluster size, we first use the Simple Replay utility to extract information on all concurrent workloads that have occurred in the past 48 hours, from one-time user queries to BI reporting queries to ETL transformations. After we extract the information from the logs of the source Amazon Redshift cluster, we replay the same workloads on various benchmark cluster configurations. We may repeat this process for other timeframes in the past, such as month-end reporting or timeframes that exhibited unexpected workload spikes. To determine the optimal cluster size, the Example Corp team observes the CPU utilization of each benchmark cluster configuration and chooses the best cluster offering the best price-to-performance ratio.

For other capabilities and functionality in psql scripts, I recommend you reach out to your AWS account SA to evaluate available benchmarking scripts in relation to your needs and perhaps avoid “reinventing the wheel.”

Conclusion

In this series of posts, we discussed a number of recommended best practices for conducting high-quality benchmark tests. Some of the best practices represented core principles that span all the open-source tools discussed (such as consistency in testing methodology). In this post, we reviewed the strengths and appropriateness of SQLWorkbench and psql for conducting benchmark tests. I hope this series has been helpful, and strongly encourage current and prospective customers to reach out to me or other AWS colleagues if you wish to delve deeper.


About the Author

Asser Moustafa is an Analytics Specialist Solutions Architect at AWS based out of Dallas, Texas. He advises customers in the Americas on their Amazon Redshift and data lake architectures and migrations, starting from the POC stage to actual production deployment and maintenance.

Getting the most out of your analytics stack with Amazon Redshift

Post Syndicated from Rajiv Gupta original https://aws.amazon.com/blogs/big-data/getting-the-most-out-of-your-analytics-stack-with-amazon-redshift/

Analytics environments today have seen an exponential growth in the volume of data being stored. In addition, analytics use cases have expanded, and data users want access to all their data as soon as possible. The challenge for IT organizations is how to scale your infrastructure, manage performance, and optimize for cost while meeting these growing demands.

As a Sr. Analytics Solutions Architect at AWS, I get to learn firsthand about these challenges and work with our customers to help them design and optimize their architecture. Amazon Redshift is often a key component in that analytics stack. Amazon Redshift has several built-in features to give you out-of-the-box performance, such as automatic workload management, automatic ANALYZE, automatic VACUUM DELETE, and automatic VACUUM SORT. These tuning features enable you to get the performance you need with fewer resources. In addition, Amazon Redshift provides the Amazon Redshift Advisor, which continuously scans your Amazon Redshift cluster and provides recommendations based on best practices. All you need to do is review the recommendations and apply the ones that provide the most benefit.

In this post, we examine a few challenges to your continually evolving analytics environment and how you can configure it to get the most out of your analytics stack by using the new innovations in Amazon Redshift.

Choosing the optimal hardware

The first area to consider is to ensure that you’ve chosen the optimal node type for your workload. Amazon Redshift has three families of node types; RA3, DC2, and DS2. The newest node type, RA3, was built for compute and storage separation so you can cost-effectively scale storage and compute to handle most analytics workloads, and should be chosen for most customers. If you have smaller datasets (< 640 GB of compressed data) or heavier compute needs, you may want to consider the DC2 nodes. Finally, the DS2 node type, while still available, is considered a legacy node type. If you’re using the DS2 node type, you should migrate to RA3 to optimize costs and performance. One of the key benefits of cloud computing is that you’re not tied to one node type. It’s very fast and efficient to migrate between one node type to another using the elastic resize functionality. Because all node types are compatible, no code changes are necessary.

For each node type, there are different sizes to consider. For the RA3 node type, there are the XLPlus, 4XLarge and 16XLarge sizes, for the DC2 node types, the Large and 8XLarge sizes and for for DS2, the XLarge and 8XLarge sizes. The following table summarizes the allocated resources for each instance type as of December 11, 2020.

Instance type Disk type Size Memory vCPUs Maximum Nodes
RA3 xlplus Managed Storage Scales to 32 TB* 32 GB 4 16
RA3 4xlarge Managed Storage Scales to 64 TB* 96 GB 12 32
RA3 16xlarge Managed Storage Scales to 128 TB* 384 GB 48 128
DC2 large SSD 160 GB 16 GB 2 32
DC2 8xlarge SSD 2.56 TB 244 GB 32 128
DS2 xlarge Magnetic 2 TB 32 GB 4 32
DS2 8xlarge Magnetic 16 TB 244 GB 36 128

When determining the node size and the number of nodes needed in your cluster, consider your processing needs. For the node type you’re using, start with the smallest node size and consider the larger node sizes when you exceed the threshold of number of nodes. For example, for the RA3.XLPlus node type, the maximum number of nodes is 16 nodes. When you exceed this, consider 6 or more of the RA3.4XLarge node. When you exceed 32 nodes of the RA3.4XLarge node type, consider 8 or more of the RA3.16XLarge node. The Amazon Redshift console (see the following screenshot) provides a helpful tool to help you size your cluster taking into consideration parameters such as the amount of storage you need as well as your workload.

Reserving compute power

Building and managing a data warehouse environment is a large cross-functional effort often involving an investment in both time and resources. Amazon Redshift provides deep discounts on the hardware needed to run your data warehouse if you reserve your instances. After you’ve evaluated your workloads and have a configuration you like, purchase Reserved Instances (RIs) for discounts from 20% to 75% when compared to on-demand. You can purchase RIs using a Full Upfront, Partial Upfront, or sometimes a No Upfront payment plan. Reserved Instances are not tied to a particular cluster and are pooled across your account. If your needs expand and you decide to increase your cluster size, simply purchase additional Reserved Instances.

In the following chart, you can compare the yearly on-demand cost of a Redshift cluster to the equivalent cost of a 1-year RI and a 3-year RI (sample charges and discounts are based on 1 node of dc2.large all upfront commitments in the us-east-1 Region as published on November 1st, 2020). If you use your cluster for more than 7.5 months of the year, you save money with the purchase of a 1-year RI. If you use your cluster for more than 4.5 months on-demand, you can save even more money with the purchase of a 3-year RI.

Managing intermittent workloads

If your workload is infrequently accessed, Amazon Redshift allows you to pause and resume your cluster. When your cluster is paused, you’re only charged for backup and storage costs. You can pause and resume your cluster using an API command, the Amazon Redshift console, or through a scheduler. One use case where this feature is useful is if you’re using Amazon Redshift as a compute engine that reads data from the Amazon Simple Storage Service (Amazon S3) data lake and unloads the results back to the data lake. In that use case, you only need the cluster running during the data curation process. Another use case where this feature may be useful is if the cluster only needs to be available when the data pipeline runs and for a reporting platform to refresh its in-memory storage.

When deciding to pause and resume your cluster, keep in mind the cost savings from Reserved Instances. In the following chart, we can compare the daily on-demand cost of an Amazon Redshift cluster to the equivalent cost of a 1-year RI and a 3-year RI when divided by the number of days in the RI (sample charges and discounts are based on 1 node of dc2.large all upfront commitments in the us-east-1 Region as published on November 1st, 2020). If you use your cluster for more than 15 hours in a day, you save money with the purchase of a 1-year RI. If you use your cluster for more than 9 hours in a day, you can save even more money with the purchase of a 3-year RI.

Managing data growth with RA3

With use cases expanding, there is more and more demand for data within the analytics environment. In many cases, data growth outpaces the compute needs. In traditional MPP systems, to manage data growth, you could add nodes to your cluster, archive old data, or make choices on which data to include. With Amazon Redshift RA3 with managed storage, instead of the primary storage being on your compute nodes, your primary storage is backed by Amazon S3, which allows for much greater storage elasticity. The compute nodes contain a high-performance SSD backed local cache of your data. Amazon Redshift automatically moves hot data to cache so that processing the hottest data is fast and efficient. This removes the need to worry about storage so you can scale your cluster based on your compute needs. Migrating to RA3 is fast and doesn’t require making any configuration changes. You simply resize your cluster and choose the node type and number of nodes for your target configuration.  The following diagram illustrates this architecture.

Managing real-time analytics with federated query

We often see the use case of wanting a unified view of your data that is accessible within your analytics environment. That data might be high-volume log or sensor data that is being streamed into the data lake, or operational data that is generated in an OLTP database. With Amazon Redshift, instead of building pipelines to ingest that data into your data warehouse, you can use you can use the federated query feature and Amazon Redshift Spectrum to expose this data as external schemas and tables for direct querying, joining, and processing. Querying data in place reduces both the storage needs and compute needs of your data warehouse. The query engine de-composes the query and determines which parts of the query processing can be run in the source system. When possible, filters and transformations are pushed down to the source. In the case of an OLTP database, any applicable filters are applied to the query in Amazon Aurora PostgreSQL or Amazon RDS for PostgreSQL. In the case of the data lake, the processing occurs in the Amazon Redshift Spectrum compute layer. The following diagram illustrates this architecture.

Managing data growth with compression

When you analyze the steps involved in running a query, I/O operations are usually the most time-consuming step. You can reduce the number of I/O operations and maximize resources in your analytics environment by optimizing storage. Amazon Redshift is a columnar store database and organizes data in 1 MB blocks. The more data that can fit in a 1 MB block, the less I/O operations are needed for reads and writes.

For every column in Amazon Redshift, you can choose the compression encoding algorithm. Because the column compression is so important, Amazon Redshift developed a new encoding algorithm: AZ64. This proprietary algorithm is intended for numeric and data/time data types. Benchmarking AZ64 against other popular algorithms (ZSTD and LZO) showed better performance and sometimes better storage savings. To apply a column encoding, you typically specify the encoding in the CREATE TABLE statement. If you don’t specifically set a column encoding, Amazon Redshift chooses the most optimal based on the data type you specified either at table creation or when it is first loaded. If you have older tables, they may not be taking advantage of the latest encoding algorithms. You can modify the encoding using the ALTER TABLE statement. The following table summarizes your storage savings and performance improvements.

Managing spiky workloads with concurrency scaling

Analytic workloads rarely have even compute requirements 24/7. Instead, spikes appear throughout the day, whether it’s because of an ingestion pipeline or a spike in user activity related to a business event that is out of your control.  

When user demand is unpredictable, you can use the concurrency scaling feature to automatically scale your cluster. When the cluster sees a spike in user activity, concurrency scaling detects that spike and automatically routes queries to a new cluster within seconds. Queries run on the concurrent cluster without any change to your application and don’t require data movement. You can configure concurrency scaling to use up to 10 concurrent clusters, but it only uses the clusters it needs for the time it needs them. When your query runs against the concurrent cluster, you only pay for the amount of time the query is run and billed per second. The following diagram illustrates this architecture.

Each cluster earns up to 1 hour of free concurrency scaling credits per day, which is sufficient for 97% of customers. You can also set up costs controls using the usage limits. This feature can alert you or even disable the feature if you exceed a certain amount of usage.

Managing spiky workloads with elastic resize

When the user demand is predictable, you can use the elastic resize feature to easily scale your cluster up and down using an API command, the console, or based on a schedule. For example, if you have an ETL workload every night that requires additional I/O capacity, you can schedule a resize to occur every evening during your ETL workload. During an elastic resize, the endpoint doesn’t change and it happens within minutes. If a session connection is running, it’s paused until the resize completes. You can then scale back down at the end of the ETL workload. The following diagram illustrates this process.

Whether it’s through elastic resize or concurrency scaling, you want to size based on your steady state compute needs, not the peaks, and use features like elastic resize and concurrency scaling.

Providing access to shared data through multiple clusters

You may have multiple groups within your organization who want to access the analytics data. One option is to load all the data into one Amazon Redshift cluster and size the cluster to meet the compute needs of all users. However, that option can be costly. Also, isolating the workloads for some of your groups provides a few benefits. Each organization can be responsible for their own cluster charges and if either group has a tight SLA, they can ensure that the other’s queries don’t cause resource contention. One solution for sharing data and isolating workloads is by using the lake house architecture. When you manage your data in a data lake, you can keep it in open formats that are easily transportable and readable by any number of analytics services. Capabilities such as Amazon Redshift Spectrum, data lake export, and INSERT (external table), enable you to easily read and write data from a shared data lake within Amazon Redshift. Each group can live query the external data and join it to any local data they may have. Each group may even consider pausing and resuming their cluster when it is not in use. The following diagram illustrates this architecture.

Amazon Redshift Spectrum even supports reading data in Apache Hudi and Delta Lake.

Summary

Tens of thousands of customers choose Amazon Redshift to power analytics across their organization, and we’re constantly innovating to meet your growing analytics needs. For more information about these capabilities and see demos of many of the optimizations, see our AWS Online Tech Talks and check out What’s New in Amazon Redshift.


About the Author

Rajiv Gupta is a data warehouse specialist solutions architect with Amazon Web Services.

Working with timestamp with time zone in your Amazon S3-based data lake

Post Syndicated from Thiyagarajan Arumugam original https://aws.amazon.com/blogs/big-data/working-with-timestamp-with-time-zone-in-your-amazon-s3-based-data-lake/

With a data lake built on Amazon Simple Storage Service (Amazon S3), you can use the purpose-built analytics services for a range of use cases, from analyzing petabyte-scale datasets to querying the metadata of a single object. AWS analytics services support open file formats such as Parquet, ORC, JSON, Avro, CSV, and more, so it’s convenient to analyze with the tool that is most appropriate for your use case. For more information, see Amazon S3 as the Data Lake Storage Platform.

The TIMESTAMP and TIMESTAMPTZ (TIMESTAMP with time zone) data types are key data elements associated with many time-based datasets (for example clickstream, historical sales, and forecasting) in your data lake. But when you access the data across different analytical services, such as Amazon EMR-based ETL outputs being read by Amazon Redshift Spectrum, you may not know how the data will behave. Furthermore, lack of proper handling may cause accuracy issues in timestamp with time zone data types. This post delves into handling the TIMESTAMP and TIMESTAMPTZ data types in the context of a data lake by using a centralized data architecture. Because AWS analytical services cover a broad spectrum, we primarily focus on handing timestamps using Apache Hive, Apache Spark, Apache Parquet (using Amazon EMR and Amazon Athena), and Amazon Redshift to cover both the data lake and data warehouse.

Overview of TIMESTAMP and TIMESTAMPTZ data types in your data lake

Let’s start with some common definitions of the TIMESTAMP and TIMESTAMPTZ data types.

  • The TIMESTAMP data type stores values that include the date and time of day. For example, 12/17/1997 17:37:16. Timestamps are presented without time zone information.
  • The TIMESTAMPTZ data type to stores values with the date, time of day, and time zone. For example, 12/17/1997 17:37:16 (PST).

Internally, the timestamp is as an integer, representing seconds in UTC since the epoch (1970-01-01 00:00:00 UTC) and TIMESTAMPTZ values also stored as integers with respect to Coordinated Universal Time (UTC).

When working with the TIMESTAMPTZ data type, reads and writes use the time zone of the client user machine. When no time zone is set up or if left at the default values (such as the JVM/SQL client), it defaults to UTC.

Timestamp behavior when accessed across the analytical services

For this post, we discuss handling the timestamp with time zone data when accessed individually within the services and as well as between the services. The following diagram shows the architecture for this setup.

In this architecture, Parquet objects are stored in a centralized Amazon S3-based data lake, and Amazon EMR, Athena, and Amazon Redshift are used to access this centralized data. Data is also processed by these individual engines and accessed across these services through the Amazon S3 storage.

In this post, we illustrate the behavior of the different data types when data moves across different services from the Amazon S3 Parquet files.

Processing data in Amazon EMR (ETL) and accessing it with Amazon Redshift

In this use case, the Spark or Hive data pipeline generates Parquet files in the data lake and stores it in Amazon S3. Parquet files that are stored in Amazon S3 are loaded to Amazon Redshift using the COPY command. The following diagram illustrates this workflow.

To test this setup, complete the following steps:

  1. Create a Hive table and insert a sample row (for this post, we use an EMR cluster spun up in us-west-2, PST):
    CREATE EXTERNAL TABLE clickstream_dwh.clickstream_hive
    (
      sessionid             BIGINT,
      click_region       STRING,
      click_datetime_utc       TIMESTAMP,
      pageid                INT,
      productid          INT
    )
    ROW FORMAT SERDE 'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe' 
    STORED AS INPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat' 
    OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetOutputFormat' 
    LOCATION s3://clickstream-dwh-us-west-2/warehouse/clickstream_dwh.db/clickstream_hive/';
    
    
    insert into clickstream_dwh.clickstream_hive values (9074420482 ,'SEATTLE, US' ,'2014-04-06 02:40:13' ,3365,183876);

  1. Verify the Parquet file content using the Parquet tool in Amazon S3:
    $ parq 000000_0 --head 10
        sessionid click_region  click_datetime_utc  pageid  productid
    0  9074420482        SEATTLE, US 2014-04-06 09:40:13    3365     183876

In the preceding output, the Hive client running Amazon EMR interprets the time zone with respect to the end-user client (in PST), and converts it to UTC when writing to the Parquet file.

  1. Read through Hive and Spark (in Pacific time):
    Read through Hive(Pacific):
    
    PST:
    select * from clickstream_dwh.clickstream_hive; 
    
    +-------------+---------------+------------------------+---------+------------+
    |  sessionid  | click_region  |   click_datetime_utc   | pageid  | productid  |
    +-------------+---------------+------------------------+---------+------------+
    | 9074420482  | SEATTLE, US         | 2014-04-06 02:40:13.0  | 3365    | 183876     |

Amazon EMR Hive and Spark convert the underlying UTC stored timestamp values in Parquet to the client user machine’s relative time (PST) when displaying the results.

  1. Copy the Parquet file to an Amazon Redshift table with the TIMESTAMP column data type (in UTC). We use the SQL command line client tool psql to query the results in Amazon Redshift.
    COPY the parquet file to Redshift table with timestamp column data type(UTC):
    
    
    CREATE TABLE clickstream_dwh.clickstream_ts
    (
      sessionid             BIGINT,
      click_region       VARCHAR(100),
      click_datetime_utc       TIMESTAMP,
      pageid                INT,
      productid          INT
    );
    
    dev=# SHOW TIMEZONE;
     TimeZone 
    ----------
     UTC
    (1 row)
    
    dev=# select * from clickstream_dwh.clickstream_ts;
     sessionid  | click_region | click_datetime_utc  | pageid | productid 
    ------------+--------------+---------------------+--------+-----------
     9074420482 | SEATTLE, US        | 2014-04-06 09:40:13 |   3365 |    183876
    (1 row)
    
    
    dev=# SET timezone = 'America/Los_Angeles';
    SET
    
    dev=# SHOW TIMEZONE;
          TimeZone       
    ---------------------
     America/Los_Angeles
    (1 row)
    
    
    dev=# select * from clickstream_dwh.clickstream_ts;
     sessionid  | click_region | click_datetime_utc  | pageid | productid 
    ------------+--------------+---------------------+--------+-----------
     9074420482 | SEATTLE, US        | 2014-04-06 09:40:13 |   3365 |    183876
    (1 row)
    
    Note: SET timezone = 'America/Los_Angeles' , does not affect the TIMESTAMP column.

In the preceding output, the timestamp doesn’t have a time zone. All data is interpreted in UTC or whatever raw format it was when loaded into Amazon Redshift.

  1. Copy the Parquet file to the Amazon Redshift table using TIMESTAMPTZ (UTC & Pacific):
    COPY the parquet file to Redshift table with TIMESTAMPTZ(UTC & Pacific):
    
    
    CREATE TABLE clickstream_dwh.clickstream_tz
    (
      sessionid             BIGINT,
      click_region       VARCHAR(100),
      click_datetime_utc       TIMESTAMPTZ,
      pageid                INT,
      productid          INT
    );
    
    
    COPY clickstream_dwh.clickstream_tz
    FROM 's3://clickstream-dwh-us-west-2/warehouse/clickstream_dwh.db/clickstream_hive/'
    IAM_ROLE 'arn:aws:iam::123456789012:role/RedshiftDemoRole'
    parquet;


    dev=# SHOW TIMEZONE;
     TimeZone 
    ----------
     UTC
    (1 row)
    
    dev=# select * from clickstream_dwh.clickstream_tz;
     sessionid  | click_region |   click_datetime_utc    | pageid | productid 
    ------------+--------------+------------------------+--------+-----------
     9074420482 | SEATTLE, US        | 2014-04-06 09:40:13+00 |   3365 |    183876
    (1 row)
    
    dev=# SET timezone = 'America/Los_Angeles';
    SET
    dev=# 
    dev=# 
    dev=# SHOW TIMEZONE;
          TimeZone       
    ---------------------
     America/Los_Angeles
    (1 row)
    
    dev=# select * from clickstream_dwh.clickstream_tz;
     sessionid  | click_region |   click_datetime_utc    | pageid | productid 
    ------------+--------------+------------------------+--------+-----------
     9074420482 | SEATTLE, US        | 2014-04-06 02:40:13-07 |   3365 |    183876
    (1 row)

The output shows that TIMESTAMPTZ can interpret the client time zone and convert the value with respect to the end-user client (PST), though the actual values are stored in UTC.

Processing data from Amazon Redshift and moving it to an Amazon S3 data lake

In the following use case, we copy data from Amazon Redshift to a data lake. Amazon Redshift stores the TIMESTAMP and TIMESTAMPTZ columns data types in a table. The table data is exported to Amazon S3 as Parquet files with the UNLOAD command. The following diagram illustrates this architecture.

To experiment with this setup, complete the following steps:

  1. Unload the Amazon Redshift table data to Amazon S3 (in UTC):
    UNLOAD ('select * from clickstream_dwh.clickstream_tz;')
    TO 's3://clickstream-dwh-us-west-2/warehouse/clickstream_dwh.db/clickstream_rs/'
    IAM_ROLE 'arn:aws:iam::123456789012:role/RedshiftDemoRole'
    parquet;

  1. Verify the Parquet file content:
Check the parquet file content:

$ parq 0016_part_00.parquet --head 10
    sessionid click_region   click_datetime_utc  pageid  productid
0  9074420482        SEATTLE, US 2014-04-06 09:40:13    3365     183876
  1. Create a table in Hive and query it (in UTC):
    CREATE EXTERNAL TABLE clickstream_dwh.clickstream_rs
    (
      sessionid             BIGINT,
      click_region       STRING,
      click_datetime_utc       TIMESTAMP,
      pageid                INT,
      productid          INT
    )
    ROW FORMAT SERDE 'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe' 
    STORED AS INPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat' 
    OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetOutputFormat' 
    LOCATION 's3://clickstream-dwh-us-west-2/warehouse/clickstream_dwh.db/clickstream_rs/';


    > set hive.parquet.timestamp.skip.conversion=false;
    
    
    > select * from clickstream_dwh.clickstream_rs;
    
    
    +-------------+---------------+------------------------+---------+------------+
    |  sessionid  | click_region  |   click_datetime_utc   | pageid  | productid  |
    +-------------+---------------+------------------------+---------+------------+
    | 9074420482  | SEATTLE, US         | 2014-04-06 02:40:13.0  | 3365    | 183876     |
    +-------------+---------------+------------------------+---------+------------+
    1 row selected (0.888 seconds)

In the preceding output, the actual data in the Parquet file is stored in UTC, but Hive can read and display the local time zone using client settings.

When using Hive, set hive.parquet.timestamp.skip.conversion=false. Pre-3.1.2 Hive implementation of Parquet stores timestamps in UTC on-file; this flag allows you to skip the conversion when reading Parquet files created from other tools that may not have done so. Setting it to false treats legacy timestamps as UTC-normalized. For more information, see hive.parquet.timestamp.skip.conversion.

  1. Query using Spark-SQL (in Pacific time):
    spark-sql> select *  from clickstream_dwh.clickstream_rs;
    
    
    9074420482	SEATTLE, US	2014-04-06 02:40:13	3365	183876

In the preceding output, Spark converts the values with respect to the end-user client (PST), though the actual values are stored in UTC.

Accessing data through Athena

To access the data through Athena, you need to create the external table either in the AWS Glue Data Catalog or Hive metastore. In this example, we populate the Data Catalog.

To create a table using the Data Catalog, sign in to the Athena console and run the following DDL:

CREATE EXTERNAL TABLE IF NOT EXISTS default.blog_clickstream(
  `sessionid` bigint,
  `click_region` string,
  `click_datetime_utc` timestamp,
  `pageid` int,
  `productid` int 
)
ROW FORMAT SERDE 'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe'
WITH SERDEPROPERTIES (
  'serialization.format' = '1'
) LOCATION 's3://clickstream-dwh-us-west-2/warehouse/clickstream_dwh.db/clickstream_rs/'
TBLPROPERTIES ('has_encrypted_data'='false');

The following screenshot shows the query results.

The results show that Athena converts click_datetime_utc to the user’s local time zone (in this case, PST).

Accessing data through Amazon Redshift Spectrum

To access the data through Amazon Redshift Spectrum, you need to create the following:

  • The external database and table in the Data Catalog or a Hive metastore. We can use the same table we already created in the preceding use case (default.blog_clickstream).
  • An Amazon Redshift external schema for the external database in the Data Catalog.

See the following code:

dev=# CREATE EXTERNAL SCHEMA ext_clickstream_blog
      from data catalog
      database 'default' 
      region 'us-west-2' 
      iam_role 'arn:aws:iam::123456789012:role/RedshiftDemoRole';


dev=#  select * from ext_clickstream_blog.blog_clickstream;

sessionid  | click_region | click_datetime_utc  | pageid | productid
-----------+--------------+---------------------+--------+----------
9074420482 | SEATTLE, US        | 2014-04-06 09:40:13 |   3365 |    183876

The output shows that Amazon Redshift Spectrum can convert click_datetime_utc to the local time zone of the user (PST).

Use cases for handling TIMESTAMP AND TIMESTAMPTZ data types

When implementing the data model for your data lake, the choice between selecting the TIMESTAMP or TIMESTAMPTZ data type depends on how your end-users consume the data. In this section, we discuss two different use cases.

Using TIMESTAMP for a uniform display of one normalized time

When you want a uniform display of a standard time (in a particular time zone), use the TIMESTAMP data type and baseline the values that are stored into a particular time zone. For example, the following table shows collected clickstream data from a global website.

sessionid click_region click_datetime_utc pageid productid
3682484416 Chennai 2014-04-06T 18:44:58 7156 309743
6367587374 London 2014-04-06T 18:44:58 5298 749625
9074420482 Los Angles 2014-04-06T 09:40:13 3365 183876
1746153004 Perth 2014-04-04T 06:13:28 3761 725195
1449344779 Singapore 2014-04-04T 06:13:28 3527 140229
4115543521 New York 2014-04-07T 09:22:28 3712 831655
2748081381 Paris 2014-04-07T 09:22:28 8474 347742
1120684200 New York 2014-04-07T 09:22:28 2731 568755

The clicks for the website come from users across the globe and are normalized for the UTC time zone using the click_datetime_utc column and a TIMESTAMP data type. You can accomplish this step during the data transformation process. Normalizing the data avoids confusion when data is analyzed across the different Regions without needing explicit conversion.

Using TIMESTAMPTZ for a contextual display of data depending on the user’s local time zone

When you need a contextual display of date and time for users accessing the data, choose the TIMESTAMPTZ data type. For example, let’s consider a customer service application that is accessing data from a centralized data warehouse. Individual users of the application are interested in analyzing data with respect which location the issue happened, rather than a normalized time zone. See the following code:

create table public.customer_issue_log
(
customer_id	BIGINT NOT NULL,
customer_location	VARCHAR(50) NOT NULL,
customer_timezone	VARCHAR(10) NOT NULL,
issue_create_time timestamptz NOT NULL,
issue_create_time_utc timestamp  NULL,
issue_id	INTEGER NOT NULL,
issue_severity INTEGER NOT NULL
);

The following table summarizes the output.

customer_id customer_location customer_timezone issue_create_time issue_create_time_utc issue_id issue_severity
9589430063 Chennai, India IST 4/5/2014 11:44:58 PM 4/6/2014 04:44:58 AM 2343 3
2796599493 New York, US EST 4/6/2014 06:44:58 AM 4/6/2014 11:44:58 AM 2780 4
1836626118 Toronto, CA EDT 4/4/2014 05:13:28 AM 4/4/2014 10:13:28 AM 7821 1
6790206978 Sydney, Australia AEDT 4/5/2014 05:40:13 PM 4/5/2014 10:40:13 PM 3135 5

The issue_create_time column stores the date and time values and the time zone. When you query this table, you can view issue_create_time in your local time zone automatically (without any explicit conversion) by configuring set timezone or using a SQL client (such as SQL Workbench) that automatically adjusts this with respect your local computer settings.

In addition, you can also introduce optional redundant columns such as issue_create_time_utc for ease of use when users try to analyze the data across different Regions.

Independent of the approach taken for the implementation, there is no loss of timestamp or time zone values when using the preceding approach, and you can perform data aggregation on both columns without needing explicit conversion because all data is stored in UTC in the underlying storage (Parquet in Amazon Redshift). For example, you can roll up data into weekly or monthly aggregates across the Regions without any explicit conversion. The following example code calculates the weekly number of issues by priority across all locations:

select date_trunc('week', issue_create_time) wk, issue_severity, count(issue_id) from public.customer_issue_log
where
group by date_trunc('week', issue_create_time), issue_severity;

Best practices for handling timestamps and time zones with data types

You should handle dates as either DATE, TIMESTAMP, or TIMESTAMPTZ data types and not convert them to strings. When dates are interpreted from strings, you lose all the features and flexiblity of working with date fields and date calculations, and also lose efficiency of processing. Moreover, casting or converting at runtime can be expensive.

When using TIMESTAMP or TIMESTAMPTZ data types, be aware of the client tools that access them. Client tool behavior largely depends on the local setting of the drivers and JVM. But it’s possible to override the behavior and always check for client tool-specific default behavior.

Use TIMESTAMPTZ only when absolutely necessary in the data model. In most use cases, TIMESTAMP simplifies data handling and avoids ambiguity when users access them.

Summary

In this post, we talked about handling and using TIMESTAMP and TIMESTAMPTZ data types with an Amazon S3-backed data lake. Most importantly, we covered how different AWS services like Amazon Redshift, Amazon EMR, Hive, and many other client tools interpret and interact with these data types. Choosing between using TIMESTAMP or TIMESTAMPTZ depends on the use case and how the end-user wants to visualize the data (a uniform display with one normalized time or a contextual display depending on time zone, respectively). Happy timestamping!


About the Authors

Thiyagarajan Arumugam is a Principal Solutions Architect at Amazon Web Services and designs customer architectures to process data at scale. Prior to AWS, he built data warehouse solutions at Amazon.com. In his free time, he enjoys all outdoor sports and practices the Indian classical drum mridangam.


Srinivasan Krishnasamy is a ‘Senior Big Data Consultant’ at Amazon Web Services. He joined AWS in 2015 and specializes in building and supporting Big Data solutions that help customers to ingest, process and analyze data at scale.


Satish Sathiya is a Product Engineer at Amazon Redshift. He is an avid big data enthusiast who collaborates with customers around the globe to achieve success and meet their data warehousing and data lake architecture needs.

Using pipes to explore, discover and find data in Amazon ES with Piped Processing Language

Post Syndicated from Viraj Phanse original https://aws.amazon.com/blogs/big-data/using-pipes-to-explore-discover-and-find-data-in-amazon-es-with-piped-processing-language/

System developers, DevOps engineers, support engineers, site reliability engineers (SREs), and IT managers make sure that the underlying infrastructure powering the applications and systems within an organization is available, reliable, secure, and scalable. To achieve these goals, you need to perform a fast and deep analysis on the underlying logs, monitoring, and observability data. Amazon Elasticsearch Service (Amazon ES) is a popular choice to store and analyze such data. However, extracting insights from Elasticsearch isn’t easy. Although Query DSL (the language used to query data stored in Elasticsearch) is powerful, it has a steep learning curve, and wasn’t designed as a human interface to easily create one-time queries and explore user data.

In this post, we discuss the newly supported Piped Processing Language (PPL) feature, powered by Open Distro for Elasticsearch, which enables you to form complex queries and quickly explore and discover data with the help of pipes.

What is Piped Processing Language?

Piped Processing Language is powered by Open Distro for Elasticsearch, an Apache 2.0-licensed distribution of Elasticsearch. PPL enables you to explore, discover, and find data stored in Elasticsearch, using a set of commands delimited by pipes ( | ).

Pipes allow you to combine two or more commands as a chain, such that the output of one command acts as an input for the next command, very similar to Unix pipes. With PPL, you can now search for keywords and feed the results from the command on the left of the pipe to the command on the right of the pipe, effectively creating a command pipeline.

Use case

As an illustration, consider a use case where you want to find out the number of hosts that are responding with HTTP 404 (Page not found) and HTTP 503 (Server Unavailability) errors, aggregate the error responses per host, and sort in the order of impact.

Using Query DSL

When you use Query DSL, the query looks similar to the following code:

GET kibana_sample_data_logs/_search
{"from":0,"size":0,"timeout":"1m","query":{"bool":{"should":[{"term":{"response.keyword":{"value":"404","boost":1}}},{"term":{"response.keyword":{"value":"503","boost":1}}}],"adjust_pure_negative":true,"boost":1}},"sort":[{"_doc":{"order":"asc"}}],"aggregations":{"composite_buckets":{"composite":{"size":1000,"sources":[{"host":{"terms":{"field":"host.keyword","missing_bucket":true,"order":"asc"}}},{"response":{"terms":{"field":"response.keyword","missing_bucket":true,"order":"asc"}}}]},"aggregations":{"request_count":{"value_count":{"field":"request.keyword"}},"sales_bucket_sort":{"bucket_sort":{"sort":[{"request_count":{"order":"desc"}}],"size":10}}}}}}

The following screenshot shows the query results.


Using PPL

You can replace the entire DSL query with a single PPL command:

source = kibana_sample_data_logs | where response='404' or response='503' | stats count(request) as request_count by host, response | sort -request_count

The following screenshot shows the query results.

Commands and functions supported by PPL

PPL supports a comprehensive set of commands, including search, where, field, rename, dedup, sort, stats, eval, head, top, and rare. These commands are read-only requests to process data and return results. The following table summarizes the purpose of each command.

Command What does it do? Example Result
search source Retrieves documents from the index. The keyword search can be ignored. source=accounts; Retrieves all documents from the accounts index.
field Keeps or removes fields from the search result. source=accounts | fields account_number, firstname, lastname; Gets account_number, firstname, and lastname fields from the search result.
dedup Removes duplicate documents defined by a field from the search result. source=accounts | dedup gender | fields account_number, gender; Removes duplicate documents with the same gender.
stats Aggregates the search results using sum, count, min, max, and avg. source=accounts | stats avg(age); Calculates the average age of all accounts.
eval Evaluates an expression and appends its result to the search result. search source=accounts | eval doubleAge = age * 2 | fields age, doubleAge; Creates a new doubleAge field for each document that is age * 2.
head Returns the first N number of results in a specified search order. search source=accounts | fields firstname, age | head; Fetches the first 10 results.
top Finds the most common values of all fields in the field list. search source=accounts | top gender; Finds the most common value of gender.
rare Finds the least common values of all fields in a field list. search source=accounts | rare gender; Finds the least common value of gender.
where Filters the search result. search source=accounts | where account_number=1 or gender="F" | fields account_number, gender; Gets all the documents from the account index.
rename Renames one or more fields in a search result. search source=accounts | rename account_number as an | fields acc; Renames the account field as acc.
sort Sorts results in a specified field. search source=accounts | sort age | fields account_number, age; Sorts all documents by age field in ascending order.

PPL also supports functions including date-time, mathematical, string, aggregate, and trigonometric, and operators and expressions.

Summary

Piped Processing Language, powered by Open Distro for Elasticsearch, has a comprehensive set of commands and functions that enable you to quickly begin extracting insights from your data in Elasticsearch. It’s supported on all Amazon ES domains running Elasticsearch 7.9 or greater. PPL also expands the capabilities of the Query Workbench in Kibana in addition to SQL. For more information, see Piped Processing Language.


About the Author

Viraj Phanse is a product management leader at Amazon Web Services for Search Services/Analytics. An avid foodie, he loves trying cuisines from around the globe. In his free time, he loves to play his keyboard and travel.

Introducing Amazon Redshift RA3.xlplus nodes with managed storage

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/introducing-amazon-redshift-ra3-xlplus-nodes-with-managed-storage/

Since we launched Amazon Redshift as a cloud data warehouse service more than seven years ago, tens of thousands of customers have built analytics workloads using it. We’re always listening to your feedback and, in December 2019, we announced our third-generation RA3 node type to provide you the ability to scale and pay for compute and storage independently. In this post, I share more about RA3, including a new smaller size node type, and information about how to get started.

RA3 nodes in Amazon Redshift

The new RA3 nodes let you determine how much compute capacity you need to support your workload and then scale the amount of storage based on your needs. The managed storage of Amazon Redshift automatically uses high-performance, SSD-based local storage as its tier-1 cache. The managed storage takes advantage of optimizations such as data block temperature, data block age, and workload patterns to optimize Amazon Redshift performance and manage data placement across tiers of storage automatically. No action or changes to existing workflows are necessary on your part.

The first member of the RA3 family was the RA3.16xlarge, and we subsequently added the RA3.4xlarge to cater to the needs of customers with a large number of workloads.

We’re now adding a new smaller member of the RA3 family, the RA3.xlplus.

This allows Amazon Redshift to deliver up to three times better price performance than other cloud data warehouses. For existing Amazon Redshift customers using DS2 instances, you get up to two times better performance and double the storage at the same cost when you upgrade to RA3. RA3 also includes AQUA (Advanced Query Accelerator) for Amazon Redshift at no additional cost. AQUA is a new distributed and hardware-accelerated cache that enables Amazon Redshift to run up to ten times faster than other cloud data warehouses by automatically boosting certain types of queries. The preview is open to all customers now, and it will be generally available in January 2021.

RA3 nodes with managed storage are a great fit for analytics workloads that require best price per performance, with massive storage capacity and the ability to scale and pay for compute and storage independently. In the past, there was pressure to offload or archive old data to other storage because of fixed storage limits, which made maintaining the operational analytics dataset and querying the larger historical dataset when needed difficult. With Amazon Redshift managed storage, we’re meeting the needs of customers that want to store more data in their data warehouse.

The new RA3.xlplus node provides 4 vCPUs and 32 GiB of RAM and addresses up to 32 TB of managed storage. A cluster with RA3.xlplus node-type can contain up to 32 of these instances, for a total storage of 1024 TB (that’s 1 petabyte!). With the new smaller RA3.xlplus instance type, it’s even easier to get started with Amazon Redshift.

The differences between RA3 nodes are summarized in the following table.

vCPU Memory Storage Quota I/O Price
(US East (N. Virginia))
ra3.xlplus 4 32 GiB 32TB RMS 0.65 GB/sec $1.086 per hour
ra3.4xlarge 12 96 GiB 64TB RMS 2 GB/sec $3.26 per hour
ra3.16xlarge 48 384 GiB 64TB RMS 8 GB/sec $13.04 per hour

Creating a new Amazon Redshift cluster

You can create a new cluster on the Amazon Redshift console or the AWS Command Line Interface (AWS CLI). For this post, I walk you through using the Amazon Redshift console.

  1. On the Amazon Redshift console, choose Clusters.
  2. Choose Create cluster.
  3. For Choose the size of the cluster, choose I’ll choose.
  4. For Node type, select your preferred node type (for this post, we select xlplus).

The following screenshot shows the Cluster configuration page for the US East (N. Virginia) Region. The price may vary slightly in different Regions.

If you have a DS2 or DC2 instance-based cluster, you can create an RA3 cluster to evaluate the new instance with managed storage. You use a recent snapshot of your Amazon Redshift DS2 or DC2 cluster to create a new cluster based on RA3 instances. We recommend using 2 nodes of RA3.xlplus for every 3 nodes of DS2.xl or 3 nodes of RA3.xlplus for every 8 nodes of DC2.large. For more information about upgrading sizes, see Upgrading to RA3 node types. You can always adjust the compute capacity by adding or removing nodes with elastic resize.

If you’re migrating to Amazon Redshift from on-premises data warehouses, you can size your Amazon Redshift cluster using the sizing widget on the Amazon Redshift console. On the Cluster configuration page, for Choose the size of the cluster, choose Help me choose.

Answer the subsequent questions on total storage size and your data access pattern in order to size your cluster’s compute and storage resource.

The sizing widget recommends the cluster configuration in the Calculated configuration summary section.

Conclusion

RA3 instances are now available in 16 AWS Regions. For the latest RA3 node type availability, see RA3 node type availability in AWS Regions.

The price varies from Region to Region, starting at $1.086 per hour per node in US East (N. Virginia). For more information, see Amazon Redshift pricing.


About the Author

BP Yau is a Data Warehouse Specialist Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.
Amazon EMR Studio (Preview): A new notebook-first IDE experience with Amazon EMR

Post Syndicated from Fei Lang original https://aws.amazon.com/blogs/big-data/amazon-emr-studio-preview-a-new-notebook-first-ide-experience-with-amazon-emr/

We’re happy to announce Amazon EMR Studio (Preview), an integrated development environment (IDE) that makes it easy for data scientists and data engineers to develop, visualize, and debug applications written in R, Python, Scala, and PySpark. EMR Studio provides fully managed Jupyter notebooks and tools like Spark UI and YARN Timeline Service to simplify debugging. EMR Studio uses AWS Single Sign-On (AWS SSO), and allows you to log in directly with your corporate credentials without signing in to the AWS Management Console.

With EMR Studio, you can run notebook code on Amazon EMR running on Amazon Elastic Compute Cloud (Amazon EC2) or Amazon EMR on Amazon Elastic Kubernetes Service (Amazon EKS), and debug your applications. For more information about Amazon EMR on Amazon EKS, see What is Amazon EMR on EKS.

EMR Studio kernels and applications run on EMR clusters, so you get the benefit of distributed data processing with the performance-optimized Apache Spark runtime that Amazon EMR provides. You can also install custom kernels and libraries, collaborate with peers using code repositories such as GitHub and Bitbucket, or run parameterized notebooks as part of scheduled workflows using orchestration services like Apache Airflow or Amazon Managed Workflows for Apache Airflow (Amazon MWAA). Administrators can set up EMR clusters that can be used by EMR Studio users, or create predefined AWS CloudFormation templates for Amazon EMR and allow you to simply choose a template for creating your own cluster.

In this post, we discuss the benefits that EMR Studio offers and we introduce to you some of its capabilities. To learn more about creating and using EMR Studios, see Use Amazon EMR Studio.

Benefits of using EMR Studio

EMR Studio offers the following benefits:

  • Set up a unified experience to develop and diagnose EMR Spark applications – Administrators can set up EMR Studio to allow you to log in using your corporate credentials without having to sign in to the AWS console. You get a single unified environment to interactively explore, process, and visualize data using notebooks, build and schedule pipelines, and debug applications without having to log in to EMR clusters.
  • Use fully managed Jupyter notebooks – With EMR Studio, you can develop analytics and data science applications in R, Python, Scala, and PySpark with fully managed Jupyter notebooks. You can take advantage of distributed processing using the performance-optimized Amazon EMR runtime for Apache Spark with Jupyter kernels and applications running on EMR clusters. you can attach notebooks to an existing cluster that uses Amazon EC2 instances, or to an EMR on EKS virtual cluster. You can also start your own clusters using templates pre-configured by administrators.
  • Collaborate with others using code repositories – From the EMR Studio notebooks environment, you can connect to code repositories such as AWS CodeCommit, GitHub, and Bitbucket to collaborate with peers.
  • Run custom Python libraries and kernels – From EMR Studio, you can install custom Python libraries or Jupyter kernels required for your applications directly to the EMR clusters.
  • Automate workflows using pipelines – EMR Studio makes it easy to move from prototyping to production. You can create EMR Studio notebooks that can be programmatically invoked with parameters, and use APIs to run the parameterized notebooks. You can also use orchestration tools such as Apache Airflow or Amazon MWAA to run notebooks in automated workflows.
  • Simplified debugging – With EMR Studio, you can debug jobs and access logs without logging in to the cluster. EMR Studio provides native application interfaces such as Spark UI and YARN Timeline. When a notebook is run in EMR Studio, the application logs are uploaded to Amazon Simple Storage Service (Amazon S3). As a result, you can access logs and diagnose applications even after your EMR cluster is terminated. You can quickly locate the job to debug by filtering based on the cluster or time when the application was run.

In the following section, we demonstrate some of the capabilities of Amazon EMR Studio using a sample notebook. For our sample notebook, we use the open-source, real-time COVID-19 US daily case reports provided by Johns Hopkins University CSSE from the following GitHub repo.

Notebook-first IDE experience with AWS SSO integration

EMR Studio makes it simple to interact with applications on an EMR cluster. After an administrator sets up EMR Studio and provides the access URL (which looks like https://es-*************************.emrstudio.us-east-1.amazonaws.com), you can log in to EMR Studio with your corporate credentials.

After you log in to EMR Studio, you get started by creating a Workspace. A Workspace is a collection of one or more notebooks for a project. The Workspaces and the notebooks that you create in EMR Studio are automatically saved in an Amazon S3 location.

Now, we create a Workspace by completing the following steps:

  1. On the EMR Studio Dashboard page, choose Create Workspace.
  2. On the Create a Workspace page, enter a Workspace name and a Description.

Naming the Workspace helps identify your project. Your workspace is automatically saved, and you can find it later on the Workspaces page. For this post, we name our Workspace EMR-Studio-WS-Demo1.

  1. On the Subnet drop-down menu, choose a subnet for your Workspace.

Each subnet belongs to the same Amazon Virtual Private Cloud (Amazon VPC) as your EMR Studio. Your administrator may have set up one or more subnets to use for your EMR clusters. You should choose a subnet that matches the subnet where you use EMR clusters. If you’re not sure about which subnet to use, contact your administrator.

  1. For S3 location, choose the Amazon S3 location where EMR Studio backs up all notebook files in the Workspace.

This location is where your Workspace and all the notebooks in the Workspace are automatically saved.

  1. In the Advanced configuration section, you can attach an EMR cluster to your Workspace.

For this post, we skip this step. EMR Studio allows you to create Workspaces and notebooks without attaching to an EMR cluster. You can attach an EMR cluster later when you’re ready to run your notebooks.

  1. Choose Create Workspace.

Fully managed environment for managing and running Jupyter-based notebooks

EMR Studio provides a fully managed environment to help organize and manage Workspaces. Workspaces are the primary building blocks of EMR Studio, and they preserve the state of your notebooks. You can create different Workspaces for each project. From within a Workspace, you can create notebooks, link your Workspace to a code repository, and attach your Workspace to an EMR cluster to run notebooks. Your Workspaces and the notebooks and settings it contains are automatically saved in the Amazon S3 location that you specify.

If you created the workspace EMR-Studio-WS-Demo1 by following the preceding steps, it appears on the Workspaces page with the name EMR-Studio-WS-Demo1 along with status Ready, creation time, and last modified timestamp.

The following table describes each possible Workspace status.

Status Meaning
Starting The Workspace is being prepared, but is not yet ready to use.
Ready You can open the Workspace to use the notebook editor. When a Workspace has a Ready status, you can open or delete it.
Attaching The Workspace is being attached to a cluster.
Attached The Workspace is attached to an EMR cluster. If a Workspace is not attached to an EMR cluster, you need to attach it to an EMR cluster before you can run any notebook code in the Workspace.
Idle

The Workspace is stopped and currently idle. When you launch an idle Workspace, the Workspace status changes from Idle to Starting to Ready.


Stopping The Workspace is being stopped.
Deleting When you delete a Workspace, it’s marked for deletion. EMR Studio automatically deletes Workspaces marked for deletion. After a Workspace is deleted, it no longer shows in the list of Workspaces.

You can choose the Workspace that you created (EMR-Studio-WS-Demo1) to open it. This opens a new web browser tab with the JupyterLab interface. The icon-denoted tabs on the left sidebar allow you to access tool panels such as the file browser or JupyterLab command palette. To learn more about the EMR Studio Workspace interface, see Understand the Workspace User Interface.

EMR Studio automatically creates an empty notebook with the same name as the Workspace. For this post, we the Workspace that we created, it automatically creates EMR-Studio-WS-Demo1.ipynb. In the following screenshot, no cluster or kernel is specified in the top right corner, because we didn’t choose to attach any cluster while creating the Workspace. You can write code in your new notebook, but before you run your code, you need to attach it to an EMR cluster and specify a kernel. To attach your workspace to a cluster, choose the EMR clusters icon on the left panel.

Linking Git-based code repositories with your Workspace

You can collaborate with your peers by sharing notebooks as code via code repositories. EMR Studio supports the following Git-based services:

This capability provides the following benefits:

  • Version control – Record code changes in a version control system so you can review the history of your changes and selectively revert them.
  • Collaboration – Share code with team members working in different Workspaces through remote Git-based repositories. Workspaces can clone or merge code from remote repositories and push changes back to those repositories.
  • Code reuse – Many Jupyter notebooks that demonstrate data analysis or machine learning techniques are available in publicly hosted repositories, such as GitHub. You can associate your Workspace with a GitHub repository to reuse the Jupyter notebooks contained in a repository.

To link Git repositories to your Workspace, you can link an existing repository or create a new one. When you link an existing repository, you choose from a list of Git repositories associated with the AWS account in which your EMR Studio was created.

We add a new repository by completing the following steps:

  1. Choose the Git icon.
  2. For Repository name¸ enter a name (for example, emr-notebook).
  3. For Git repository URL, enter the URL for the Git repo (for this post, we use the sample notebook at https://github.com/emrnotebooks/notebook_execution).
  4. For Git credentials, select your credentials. Because we’re using a public repo, we select Use a public repository without credentials.
  5. Choose Add repository.

After it’s added, we can see the repo on the Git repositories drop-down menu.

  1. Choose the repo to link to the Workspace.

You can link up to three Git repositories with an EMR Studio Workspace. For more information, see Link Git-Based Repositories to an EMR Studio Workspace.

  1. Choose the File browser icon to locate the Git repo we just linked.

Attaching and detaching Workspaces to and from EMR clusters

EMR Studio kernels and applications run on EMR clusters, so you get the benefit of distributed data processing using the performance-optimized EMR runtime for Apache Spark. You can attach your Workspace to an EMR cluster and get distributed data processing using Spark or custom kernels. You can use primary node capacity to run non-distributed applications.

In addition to using Amazon EMR clusters running on Amazon EC2, you can attach a Workspace to an Amazon EMR on EKS virtual cluster to run notebook code. For more information about how to use an Amazon EMR on EKS cluster in EMR Studio, see Use an Amazon EMR on EKS Cluster to Run Notebook Code.

Before you can run your notebooks, you must attach your Workspace to an EMR cluster. For more information about clusters, see Create and Use Clusters with EMR Studio.

To run the Git repo notebooks that we linked in the previous step, complete the following steps:

  1. Choose the EMR cluster
  2. Attach the Workspace to an existing EMR cluster running on Amazon EC2 instances.
  3. Open the notebook demo_pyspark.ipynb from the Git repo emr-notebook that we linked to the Workspace.

In the upper right corner of the Workspace UI, we can see the ID of the EMR cluster being attached to our Workspace, as well as the kernel selected to run the notebook.

  1. Record the value of the cluster ID (for example, <j-*************>).

We use this value later to locate the EMR cluster for application debugging purposes.

You can also detach the Workspace from the cluster in the Workspace UI and re-attach it to another cluster. For more information, see Detach a Cluster from Your Workspace.

Being able to easily attach and detach to and from any EMR cluster allows you to move any workload from prototyping into production. For example, you can start your prototype development by attaching your workspace to a development EMR cluster and working with test datasets. When you’re ready to run your notebook with larger production datasets, you can detach your workspace from the development EMR cluster and attach it to a larger production EMR cluster.

Installing and loading custom libraries and kernels

You can install notebook-scoped libraries with a PySpark kernel in EMR Studio. The libraries installed are isolated to your notebook session and don’t interfere with libraries installed via EMR bootstrap actions, or libraries installed by other EMR Studio notebook sessions that may be running on the same EMR cluster. After you install libraries for your Workspace, they’re available for other notebooks in the Workspace in the same session.

Our sample notebook demo_pyspark.ipynb is a Python script. It uses real-time COVID-19 US daily case reports as input data. The following parameters are defined in the first cell:

  • DATE – The given date used when the notebook job is started.
  • TOP_K – The top k US states with confirmed COVID-19 cases. We use this to plot Graph a.
  • US_STATES – The names of the specific US states being checked for the fatality rates of COVID-19 patients. We use this plot Graph b.

The parameters can be any of the Python data types.

Running this notebook plots two graphs:

  • Graph a – Visualizes the top k US states with most the COVID-19 cases on a given date
  • Graph b – Visualizes the fatality rates among specific US states on a given date

In our notebook, we install notebook-scoped libraries by running the following code from within a notebook cell:

sc.install_pypi_package("pandas==0.25.1")
sc.install_pypi_package("requests==2.24.0")
sc.install_pypi_package("numpy==1.19.1")
sc.install_pypi_package("kiwisolver==1.2.0")
sc.install_pypi_package("matplotlib==3.3.0")

We use these libraries in the subsequent cells for the further data analysis and visualization steps in the notebook.

The following set of parameters is used to run the notebook:

{"DATE": "10-15-2020",
 "TOP_K": 6,
"US_STATES": ["Wisconsin", "Texas", "Nevada"]}

Running all the notebook cells generates two graphs. Graph a shows the top six US states with confirmed COVID-19 cases on October 15, 2020.

Graph b shows the fatality rates of COVID-19 patients in Texas, Wisconsin, and Nevada on October 15, 2020.

EMR Studio also allows you to install Jupyter notebook kernels and Python libraries on a cluster primary node, which makes your custom environment available to any EMR Studio Workspace attached the cluster. To install the sas_kernel kernel on a cluster primary node, run the following code within a notebook cell:

!/emr/notebook-env/bin/pip install sas_kernel

The following screenshot shows your output.

For more information about how to install kernels and use libraries, see Installing and Using Kernels and Libraries.

Diagnosing applications and jobs with EMR Studio

In EMR Studio, you can quickly debug jobs and access logs without logging in to the cluster, such as setting up a web proxy through an SSH connection, for both active and stopped clusters. You can use native application interfaces such as Spark UI and YARN Timeline Service directly from EMR Studio. EMR Studio also allows you to quickly locate the cluster or job to debug by using filters such as cluster state, creation time, and cluster ID. For more information, see Diagnose Applications and Jobs with EMR Studio.

Now, we show you how to open a native application interface to debug the notebook job that already finished.

  1. On the EMR Studio page, choose Clusters.

A list appears with all the EMR clusters launched under the same AWS account. You can filter the list by cluster state, cluster ID, or creation time range by entering values in the provided fields.

  1. Choose the cluster ID of the EMR cluster that we attached to the Workspace EMR-Studio-WS-Demo1 for running notebook demo_pyspark.ipynb.
  2. For Spark job debugging, on the Launch application UIs menu, choose Spark History Server.

The following screenshot shows you the Spark job debugging UI.

We can traverse the details for our notebook application by checking actual logs from the Spark History Server, as in the following screenshot.

  1. For Yarn application debugging, on the Launch application UIs menu, choose Yarn Timeline Server.

The following screenshot shows the Yarn debugging UI.

Orchestrating analytics notebook jobs to build ETL production pipelines

EMR Studio makes it easy for you to move any analytics workload from prototyping to production. With EMR Studio, you can run parameterized notebooks as part of scheduled workflows using orchestration services like AWS Step Functions and Apache Airflow or Amazon MWAA.

In this section, we show a simple example of how to orchestrate running notebook workflows using Apache Airflow.

We have a fully tested notebook under an EMR Studio Workspace, and want to schedule a workflow that runs the notebook on an on-demand EMR cluster every 10 minutes.

Record the value of the Workspace ID (for example, e-*****************************) and the notebook file path relative to the home directory within the Workspace (for example, demo.ipynb or my_folder/demo.ipynb)

The workflow that we create takes care of the following tasks:

  1. Create an EMR cluster.
  2. Wait until the cluster is ready.
  3. Start running a notebook defined by the Workspace ID, notebook file path, and the cluster created.
  4. Wait until the notebook is complete.

The following screenshot is the tree view of this example DAG. The DAG definition is available on the GitHub repo. Make sure you replace any placeholder values with the actual ones before using.

When you open the Gantt chart of one of the successful notebooks, we can see the timeline of our workflow. The time spent creating the cluster and creating a notebook execution is negligible compared to the time spent waiting for the cluster to be ready and waiting for the notebook to finish, which meets the expectation of our SLA.

This example is a just starting point. Try it out and extend it with more sophisticated workflows that suit your needs.

Summary

In this post, we highlighted some of the capabilities of EMR Studio, such as the ability to log in via AWS SSO, access fully managed Jupyter notebooks, link Git-based code repositories, change clusters, load custom Python libraries and kernels, diagnose clusters and jobs using native application UIs, and orchestrate notebook jobs using Apache Airflow or Amazon MWAA.

There is no additional charge for using EMR Studio in public preview, and you only pay for the use of the EMR cluster or other AWS services such as AWS Service Catalog. For more information, see the EMR Studio FAQs.

EMR Studio is available on Amazon EMR release version 6.2 and later, in the US East (N. Virginia), US West (Oregon), and EU (Ireland) Regions for public preview. For the latest Region availability for the public preview, see Considerations.

If you have questions or suggestions, feel free to leave a comment.


About the  Authors

Fei Lang is a Senior Big Data Architect at Amazon Web Services. She is passionate about building the right big data solution for customers. In her spare time, she enjoys the scenery of the Pacific Northwest, going for a swim, and spending time with her family.


Shuang Li is a Senior Product Manager for Amazon EMR at AWS. She holds a doctoral degree in Computer Science and Engineering from Ohio State University.


Ray Liu is a Software Development Engineer at AWS. Besides work, he enjoys traveling and spending time with family.


Kendra Ellis is a Programmer Writer at AWS.


Get up to 3x better price performance with Amazon Redshift than other cloud data warehouses

Post Syndicated from Eugene Kawamoto original https://aws.amazon.com/blogs/big-data/get-up-to-3x-better-price-performance-with-amazon-redshift-than-other-cloud-data-warehouses/

Since we announced Amazon Redshift in 2012, tens of thousands of customers have trusted us to deliver the performance and scale they need to gain business insights from their data. Amazon Redshift customers span all industries and sizes, from startups to Fortune 500 companies, and we work to deliver the best price performance for any use case. Earlier in 2020, we published a blog post about improved speed and scalability in Amazon Redshift. This includes optimizations such as dynamically adding cluster capacity when you need it with concurrency scaling, making sure you use cluster resources efficiently with automatic workload management (WLM), and automatically adjusting data layout, distribution keys, and query plans to provide optimal performance for a given workload. We also described how customers, including Codeacademy, OpenVault, Yelp, and Nielsen, have taken advantage of Amazon Redshift RA3 nodes with managed storage to scale their cloud data warehouses and reduce costs.

In addition to improving performance and scale, we are constantly looking at how to also improve the price performance that Amazon Redshift provides. One of the ways we ensure that we provide the best value for customers is to measure the performance of Amazon Redshift and other cloud data warehouses regularly using queries derived from industry-standard benchmarks such as TPC-DS. We completed our most recent tests based on the TPC-DS benchmark in November using the latest version of the products available across the vendors tested at that time. For Amazon Redshift, this includes more than 15 new capabilities released this year prior to November, but not new capabilities announced during AWS re:Invent 2020.

Best Out-of-the-Box and Tuned Price Performance

The test completed in November showed that Amazon Redshift delivers up to three times better price performance out-of-the-box than other cloud data warehouses. The following chart illustrates these findings.

For this test, we ran all 99 queries from the TPC-DS benchmark against a 3 TB data set. We calculated price performance by multiplying the time required to run all queries in hours by the price per hour for each cloud data warehouse. We used clusters with comparable hardware characteristics for each data warehouse. We also used default settings for each cloud data warehouse, except we enabled encryption for all four services because it’s on for two by default, and we disabled result caching where applicable. The default settings allowed us to determine the price performance delivered with no manual tuning effort. We selected the best result out of three runs for each query in order to take advantage of optimizations provided by each service. Finally, to ensure an apples-to-apples comparison, we used public pricing, and compared price performance rather than performance alone. For Amazon Redshift specifically, we used on-demand pricing; Amazon Redshift Reserved Instance pricing provides up to a 60% discount vs. on-demand pricing.

These results show that Amazon Redshift provides the best price performance out-of-the-box, even for a comparatively small 3 TB dataset. This means that you can benefit from Amazon Redshift’s leading price performance from the start without manual tuning.

You can also take advantage of performance tuning techniques for Amazon Redshift to achieve even better results for your workloads. We repeated the benchmark test using tuning best practices provided by each cloud data warehouse vendor. After all cloud data warehouses are tuned, Amazon Redshift has 1.5 times better price performance than the nearest cloud data warehouse competitor, as shown in the following chart.

As with all benchmarks, transparency and reproducibility are crucial. For this reason, we have made the data and queries available on GitHub for anyone to use. See the README in GitHub for detailed instructions on re-running these benchmarks.

Tuned price performance improves as your data warehouse grows

One critical aspect of a data warehouse is how it scales as your data grows. Will you be paying more per TB as you add more data, or will your costs remain consistent and predictable? We work to make sure that Amazon Redshift delivers not only strong performance as your data grows, but also consistent price performance. We tested Amazon Redshift price performance using TPC-DS with 3 TB, 30 TB, and 100 TB datasets on three different cluster sizes. As shown in the following graph, Amazon Redshift tuned price performance improved (from $2.80 to $2.41 per TB per run) as the datasets grew. Tuning reduces the amount of network and disk I/O required for a given workload, and has varying impact depending on the combination of workload and cluster size.

In addition, as shown in the following table, Amazon Redshift out-of-the-box price performance is nearly the same ($4.80 to $5.01 per TB per run) for all three dataset sizes. This linear scaling of price performance across data size and cluster size, both out-of-the-box and tuned, makes sure that Amazon Redshift will scale predictably as your data and workloads grow.

Amazon Redshift TPC-DS benchmark results, November 2020
  Out-of-Box Tuned
Data set
(TB)
Cluster Runtime
(sec)
Price per TB per run Runtime
(sec)
Price per TB per run
3 10 node ra3.4xlarge 1591 $4.80 926 $2.80
30 5 node ra3.16xlarge 8291 $5.01 4198 $2.53
100 10 node ra3.16xlarge 13,343 $4.83 6644 $2.41

You can learn more about Amazon Redshift’s performance on large datasets in How Amazon Redshift powers large-scale analytics for Amazon.com. This AWS re:Invent 2020 session shows how Amazon.com is using Amazon Redshift to keep up with exploding data growth, and how you can upgrade your existing data warehouse workloads to RA3 nodes to get scale and performance at great value.

Up to 10x better query performance with AQUA

We’re investing to make sure Amazon Redshift continues to improve as your data warehouse needs grow. As noted earlier, these benchmark results reflect the latest version of Amazon Redshift as of November, 2020. This version includes more than 15 new features released earlier this year, such as distributed bloom filters, vectorized queries, and automatic WLM, but doesn’t include the benefits from new capabilities announced during AWS re:Invent 2020. You can join What’s new with Amazon Redshift at AWS re:Invent 2020 to learn more about the new capabilities.

These new capabilities include AQUA (Advanced Query Accelerator) for Amazon Redshift. AQUA is a new distributed and hardware-accelerated cache for Amazon Redshift that delivers up to 10x better query performance than other cloud data warehouses. AQUA takes a new approach to cloud data warehousing. AQUA brings the compute to storage by doing a substantial share of data processing in-place on the innovative cache. In addition, it uses AWS-designed processors and a scale-out architecture to accelerate data processing beyond anything traditional CPUs can do today. AQUA’s preview is now open to all customers, and AQUA will be generally available in January 2021. You can learn more about AQUA and other new Amazon Redshift capabilities by joining What’s new with Amazon Redshift at AWS re:Invent 2020.

Price performance continues to improve

We’re investing to make sure Amazon Redshift continues to improve as your data warehouse needs grow. As noted earlier, these benchmark results reflect the latest version of Amazon Redshift as of November, 2020. This version includes more than 15 new features released earlier this year, such as distributed bloom filters, vectorized queries, and automatic WLM, but doesn’t include the benefits from new capabilities announced during AWS re:Invent 2020. You can join What’s new with Amazon Redshift at AWS re:Invent 2020 to learn more about the new capabilities.

Find the best price performance for your workloads

You can reproduce the results above using the data and queries available on GitHub.

Each workload has unique characteristics, so if you’re just getting started, a proof of concept is the best way to understand how Amazon Redshift performs for your requirements. When running your own proof of concept, it’s important that you focus on proper cluster sizing and the right metrics—query throughput (number of queries per hour) and price performance. You can make a data-driven decision by requesting assistance with a proof of concept or working with a system integration and consulting partner.

If you’re an existing Amazon Redshift customer, connect with us for a free optimization session and briefing on the new features announced at AWS re:Invent 2020.

To stay up-to-date with the latest developments in Amazon Redshift, subscribe to the What’s New in Amazon Redshift RSS feed.


About the Authors

Eugene Kawamoto is a director of product management for Amazon Redshift. Eugene leads the product management and database engineering teams at AWS. He has been with AWS for ~8 years supporting analytics and database services both in Seattle and in Tokyo. In his spare time, he likes running trails in Seattle, loves finding new temples and shrines in Kyoto, and enjoys exploring his travel bucket list.


Stefan Gromoll is a Senior Performance Engineer with Amazon Redshift where he is responsible for measuring and improving Redshift performance. In his spare time, he enjoys cooking, playing with his three boys, and chopping firewood.
Create, train, and deploy machine learning models in Amazon Redshift using SQL with Amazon Redshift ML

Post Syndicated from Debu Panda original https://aws.amazon.com/blogs/big-data/create-train-and-deploy-machine-learning-models-in-amazon-redshift-using-sql-with-amazon-redshift-ml/

Amazon Redshift is the most popular, fully managed, and petabyte-scale data warehouse. Tens of thousands of customers use Amazon Redshift to process exabytes of data every day to power their analytics workloads. Data analysts and database developers want to leverage this data to train machine learning (ML) models, which can then be used to generate insights on new data for use cases such as forecasting revenue, predicting customer churn, and detecting anomalies.

Amazon Redshift ML makes it easy for SQL users to create, train, and deploy ML models using familiar SQL commands. Amazon Redshift ML allows you to use your data in Amazon Redshift with Amazon SageMaker, a fully managed ML service, without requiring you to become experts in ML. This post shows you how you use familiar SQL statements to create and train ML models from data in Amazon Redshift and use these models to make in-database predictions on new data for use cases such as churn prediction and fraud risk scoring.

ML use cases relevant to data warehousing

You may use different ML approaches according to what’s relevant for your business, such as supervised, unsupervised, and reinforcement learning. With this release, Amazon Redshift ML supports supervised learning, which is most commonly used in enterprises for advanced analytics. As evident in the following diagram, supervised learning is preferred when you have a training dataset and an understanding of how specific input data predicts various business outcomes. The inputs used for the ML model are often referred to as features, and the outcomes or results are called targets or labels. Your training dataset is a table or a query whose attributes or columns comprise features, and targets are extracted from your data warehouse. The following diagram illustrates this architecture.

You can use supervised training for advanced analytics use cases ranging from forecasting and personalization to customer churn prediction. Let’s consider a customer churn prediction use case. The columns that describe customer information and usage are features, and the customer status (active vs. inactive) is the target or label.

The following table shows different types of use cases and algorithms used.

Use Case Algorithm / Problem Type
Customer churn prediction Classification
Predict if a sales lead will close Classification
Fraud detection Classification
Price and revenue prediction Linear regression
Customer lifetime value prediction Linear regression
Detect if a customer is going to default a loan Logistic regression

Current ways to use ML in your data warehouse

You may rely on ML experts to build and train models on your behalf or invest a lot of time learning new tools and technology to do so yourself. For example, you might need to identify the appropriate ML algorithms in SageMaker or use Amazon SageMaker Autopilot for your use case, and then export the data from your data warehouse and prepare the training data to work with these model types.

Data analysts and database developers are familiar with SQL. Unfortunately, you often have to learn a new programming language (such as Python or R) to build, train, and deploy ML models in SageMaker. When the model is deployed and you want to use it with new data for making predictions (also known as inference), you need to repeatedly move the data back and forth between Amazon Redshift and SageMaker through a series of manual and complicated steps:

  1. Export training data to Amazon Simple Storage Service (Amazon S3).
  2. Train the model in SageMaker.
  3. Export prediction input data to Amazon S3.
  4. Use prediction in SageMaker.
  5. Import predicted columns back into the database.

The following diagram illustrates this workflow.

This iterative process is time-consuming and prone to errors, and automating the data movement can take weeks or months of custom coding that then needs to be maintained. Amazon Redshift ML enables you to use ML with your data in Amazon Redshift without this complexity.

Introducing Amazon Redshift ML

To create an ML model, as a data analyst, you can use a simple SQL query to specify the data in Amazon Redshift you want to use as the data inputs to train your model and the output you want to predict. For example, to create a model that predicts customer churn, you can query columns in one or more tables in Amazon Redshift that include the customer profile information and historical account activity as the inputs, and the column showing whether the customer is active or inactive as the output you want to predict.

When you run the SQL command to create the model, Amazon Redshift ML securely exports the specified data from Amazon Redshift to Amazon S3 and calls SageMaker Autopilot to automatically prepare the data, select the appropriate pre-built algorithm, and apply the algorithm for model training. Amazon Redshift ML handles all the interactions between Amazon Redshift, Amazon S3, and SageMaker, abstracting the steps involved in training and compilation. After the model is trained, Amazon Redshift ML makes it available as a SQL function in your Amazon Redshift data warehouse by compiling it via Amazon SageMaker Neo. The following diagram illustrates this solution.

Benefits of Amazon Redshift ML

Amazon Redshift ML provides the following benefits:

  • Allows you to create and train ML models with simple SQL commands without having to learn external tools
  • Provides you with flexibility to use automatic algorithm selection
  • Automatically preprocesses data and creates, trains, and deploys models
  • Enables advanced users to specify problem type
  • Enables ML experts such as data scientists to select algorithms such as XGBoost and specify hyperparameters and preprocessors
  • Enables you to generate predictions using SQL without having to ship data outside your data warehouse
  • Allows you to pay only for training; prediction is included with the costs of your cluster (typically, ML predictions drive cost in production)

In this post, we look at a simple example that you can use to get started with Amazon Redshift ML.

To train data for a model that predicts customer churn, SageMaker Autopilot preprocesses the training data, finds the algorithm that provides the best accuracy, and applies it to the training data to build a performant model.

We provide step-by-step guidance to create a cluster, create sample schema, load data, create your first ML model in Amazon Redshift, and invoke the prediction function from your queries.

Prerequisites for enabling Amazon Redshift ML

As an Amazon Redshift administrator, the following steps are required to create your Amazon Redshift cluster for using Amazon Redshift ML:

  1. On the Amazon S3 console, create an S3 bucket that Amazon Redshift ML uses for uploading the training data that SageMaker uses to train the model. For this post, we name the bucket redshiftml-<your_account_id>. Ensure that you create your S3 bucket in the same AWS region where you will create your Amazon Redshift cluster.
  2. Create an AWS Identity and Access Management (IAM role) named RedshiftML with the policy that we provided below. While it is easy to get started with AmazonS3FullAccess and AmazonSageMakerFullAccess, we recommend using a minimal policy that we provided below (If you already have an existing IAM role, then just add these to that role):

To use or modify this policy, replace <your-account-id> with your AWS account number. Note that the policy assumes that you have created the IAM role with the name RedshiftML and the S3 bucket with the name redshiftml-<your_account_id>. The S3 bucket redshift-downloads is from where we will load the sample data used in this blog.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "cloudwatch:PutMetricData",
                "ecr:BatchCheckLayerAvailability",
                "ecr:BatchGetImage",
                "ecr:GetAuthorizationToken",
                "ecr:GetDownloadUrlForLayer",
                "logs:CreateLogGroup",
                "logs:CreateLogStream",
                "logs:DescribeLogStreams",
                "logs:PutLogEvents",
                "sagemaker:*Job*"
            ],
            "Resource": "*"
        },
        {
            "Effect": "Allow",
            "Action": [
                "iam:PassRole",
                "s3:AbortMultipartUpload",
                "s3:GetObject",
                "s3:DeleteObject",
                "s3:PutObject"
            ],
            "Resource": [
                "arn:aws:iam::<your-account-id>:role/Redshift-ML",
                "arn:aws:s3:::redshiftml-<your-account-id>/*",
                "arn:aws:s3:::redshift-downloads/*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "s3:GetBucketLocation",
                "s3:ListBucket"
            ],
            "Resource": [
                "arn:aws:s3:::redshiftml-<your-account-id>",
                "arn:aws:s3:::redshift-downloads"
            
            ]
        }
    ]
} 

For instructions, see Creating IAM roles.

  1. Choose Edit trust relationship
  2. Enter the following trust relationship definition to trust SageMaker:
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Principal": {
            "Service": [
              "redshift.amazonaws.com",
              "sagemaker.amazonaws.com"
            ]
          },
          "Action": "sts:AssumeRole"
        }
      ]
    }

  1. On the Amazon Redshift console, create a new Amazon Redshift cluster.
  2. Attach the IAM policy that you created earlier (RedshiftML).
  3. Create the cluster with the preview track (SQL_PREVIEW).
  4. You can select the preview by turning off default configuration and choosing the maintenance option.

When your cluster creation is complete and the cluster is up and running, you can create accounts for data analysts on an Amazon Redshift cluster. For this post, we create a user named demouser.

  1. Use the Amazon Redshift query editor or your preferred SQL client to connect to Amazon Redshift as an administrator and run the following command:
create user demouser with password '<yourpassword>';
  1. Grant CREATE MODEL privileges to your users. The following code grants privileges to the demouser user for creating a model:
    GRANT CREATE MODEL TO demouser;

Loading sample data

We use a customer churn model in this post. As an admin or database developer, you have to first create the schema and load data into Amazon Redshift. This dataset is attributed to the University of California Irvine Repository of Machine Learning Datasets. We have modified this data for use with Amazon Redshift ML.

  1. Create a schema named demo_ml that stores the example table and the ML model that we create:
    CREATE SCHEMA DEMO_ML;

In the next steps, we create the sample table and load data into the table that we use to train the ML model.

  1. Create the table in the demo_ml schema:
    CREATE TABLE demo_ml.customer_activity (
    state varchar(2), 
    account_length int, 
    area_code int,
    phone varchar(8), 
    intl_plan varchar(3), 
    vMail_plan varchar(3),
    vMail_message int, 
    day_mins float, 
    day_calls int, 
    day_charge float,
    total_charge float,
    eve_mins float, 
    eve_calls int, 
    eve_charge float, 
    night_mins float,
    night_calls int, 
    night_charge float, 
    intl_mins float, 
    intl_calls int,
    intl_charge float, 
    cust_serv_calls int, 
    churn varchar(6),
    record_date date);

  1. Load the sample data by using the following command. Replace your IAM role and account ID appropriate for your environment.
    COPY DEMO_ML.customer_activity 
    FROM 's3://redshift-downloads/redshift-ml/customer_activity/' 
    IAM_ROLE 'arn:aws:iam::<accountid>:role/RedshiftML' delimiter ',' IGNOREHEADER 1  
    region 'us-east-1';

  1. The demouser user should also have the usual SELECT access to the tables with the data used for training:
    GRANT SELECT on demo_ml.customer_activity TO demouser;

  1. You need to also grant CREATE and USAGE on the schema to allow users to create models and query using the ML inference functions on the demo_ml schema:
    GRANT CREATE, USAGE ON SCHEMA demo_ml TO demouser;

Now the analyst (demouser) can train a model.

Creating and training your first ML model

Use your favorite SQL client to connect to your Amazon Redshift cluster as the demouser user that your admin created. You have to run the following command to create your model named customer_churn_model:

CREATE MODEL demo_ml.customer_churn_model
FROM (SELECT state,
             area_code,
             total_charge/account_length AS average_daily_spend, 
             cust_serv_calls/account_length AS average_daily_cases,
             churn 
      FROM demo_ml.customer_activity
         WHERE record_date < '2020-01-01' 

     )
TARGET churn
FUNCTION predict_customer_churn
IAM_ROLE 'arn:aws:iam::<accountID>:role/RedshiftML'
SETTINGS (
  S3_BUCKET 'redshiftml-<your-account-id>'
)
;

The SELECT query in the FROM clause specifies the training data. The TARGET clause specifies which column is the label that the CREATE MODEL builds a model to predict. The other columns in the training query are the features (input) used for the prediction. In this example, the training data provides the features state, area code, average daily spend, and average daily cases for the customers that have been active accounts for earlier than January 1, 2020. The target column churn indicates whether the customer still has an active membership or has suspended their membership. For more information about CREATE MODEL syntax, see Amazon Redshift developers guide. After the model is created, you can run queries to make predictions.

Checking the status of your ML model

You can check the status of your models by running the SHOW MODEL command from your SQL prompt.

Enter the SHOW MODEL ALL command to see all the models that you have access to:

SHOW MODEL ALL
SchemaName ModelName
demo_ml customer_churn_model

Enter the SHOW MODEL command with your model name to see the status for a specific model:

SHOW MODEL demo_ml.customer_churn_model

The following output provides the status of your model:

Key						Value
Model Name				customer_churn_model
Schema Name				demo_ml
Owner					awsuser
Creation Time			"Tue, 24.11.2020 07:02:51"
Model State				READY
validation:			
f1,						0.681240
Estimated Cost			0.990443
TRAINING DATA:,
Query	"SELECT STATE, AREA_CODE, TOTAL_CHARGE/ACCOUNT_LENGTH AS AVERAGE_DAILY_SPEND, CUST_SERV_CALLS/ACCOUNT_LENGTH AS AVERAGE_DAILY_CASES, CHURN"
FROM DEMO_ML.CUSTOMER_ACTIVITY
WHERE ACCOUNT_LENGTH > 120
Target Column,			CHURN

PARAMETERS:,
Model Type					auto
Problem Type				BinaryClassification
Objective					F1
Function Name				predict_customer_churn
Function Parameters,		"state area_code average_daily_spend  
average_daily_cases "
Function Parameter Types 	"varchar int4 float8 int4 "
IAM Role					arn:aws:iam::99999999999:role/RedshiftML
s3 Bucket					redshiftml

Testing

Evaluating your model performance

You can see the F1 value for the example model customer_churn_model in the output of the SHOW MODEL command. The F1 amount signifies the statistical measure of the precision and recall of all the classes in the model. The value ranges between 0–1; the higher the score, the better the accuracy of the model.

You can use the following example SQL query as an illustration to see which predictions are incorrect based on the ground truth:

WITH infer_data AS (
  SELECT area_code ||phone  accountid, churn,
    demo_ml.predict_customer_churn( 
          state,
          area_code, 
          total_charge/account_length , 
          cust_serv_calls/account_length ) AS predicted
  FROM demo_ml.customer_activity
WHERE record_date <  '2020-01-01'

)
SELECT *  FROM infer_data where churn!=predicted;

Invoking your ML model for inference

You can use your SQL function to apply the ML model to your data in queries, reports, and dashboards. For example, you can run the predict_customer_churn SQL function on new customer data in Amazon Redshift regularly to predict customers at risk of churning and feed this information to sales and marketing teams so they can take preemptive actions, such as sending these customers an offer designed to retain them.

For example, you can run the following query to predict which customers in area_code 408 might churn:

SELECT area_code ||phone  accountid, 
       demo_ml.predict_customer_churn( 
          state,
          area_code, 
          total_charge/account_length , 
          cust_serv_calls/account_length )
          AS "predictedActive"
FROM demo_ml.customer_activity
WHERE area_code='408' and record_date > '2020-01-01';

The following output shows the account ID and whether the account is predicted to remain active.

accountId predictedActive
408393-7984 False.
408357-3817 True.
408418-6412 True.
408395-2854 True.
408372-9976 False.
408353-3061 True.

Providing privileges to invoke the prediction function

As the model owner, you can grant EXECUTE on the prediction function to business analysts to use the model. The following code grants the EXECUTE privilege to marketing_analyst_grp. The marketing_analyst_grp should have the USAGE granted on the demo_ml schema:

GRANT EXECUTE demo_ml.predict_customer_churn TO marketing_analyst_grp

Cost control

Amazon Redshift ML leverages your existing cluster resources for prediction so you can avoid additional Amazon Redshift charges. There is no additional Amazon Redshift charge for creating or using a model, and prediction happens locally in your Amazon Redshift cluster, so you don’t have to pay extra unless you need to resize your cluster.

The CREATE MODEL request uses SageMaker for model training and Amazon S3 for storage, and incurs additional expense. The cost depends on the number of cells in your training data, where the number of cells is the product of the number of records (in the training query or table) times the number of columns. For example, if the SELECT query of the CREATE MODEL produces 10,000 records for training and each record has five columns, then the number of cells in the training data is 50,000. You can control the training cost by setting the MAX_CELLS. If you don’t, the default value of MAX_CELLS is 1 million.

If the training data produced by the SELECT query of the CREATE MODEL exceeds the MAX_CELLS limit you provided (or the default one million, in case you didn’t provide one) the CREATE MODEL randomly chooses approximately MAX_CELLS divided by number of columns records from the training dataset and trains using these randomly chosen tuples. The random choice ensures that the reduced training dataset doesn’t have any bias. Therefore, by setting the MAX_CELLS, you can keep your cost within your limits. See the following code:

CREATE MODEL demo_ml.customer_churn_model
FROM (SELECT state,
             area_code,
             total_charge/account_length AS average_daily_spend, 
             cust_serv_calls/account_length AS average_daily_cases,
             churn 
      FROM demo_ml.customer_activity
      WHERE account_length > 120 
     )
TARGET churn
FUNCTION predict_customer_churn
IAM_ROLE 'arn:aws:iam::<acountID>:role/RedshiftML'
SETTINGS (
  S3_BUCKET 'redshiftml_<your_account_id>',
   MAX_CELLS 10000
)
;

For more information about costs associated with various cell numbers and free trial details, see Amazon Redshift pricing.

An alternate method of cost control is the MAX_RUNTIME parameter, also specified as a CREATE MODEL setting. If the training job in SageMaker exceeds the specified MAX_RUNTIME seconds, the CREATE MODEL ends the job.

The prediction functions run within your Amazon Redshift cluster, and you don’t incur additional expense there.

Customer feedback

“At Rackspace Technology we help companies elevate their AI/ML operations. We’re excited about the new Amazon Redshift ML feature because it will make it easier for our mutual Redshift customers to use ML on their Redshift with a familiar SQL interface. The seamless integration with Amazon SageMaker will empower data analysts to use data in new ways, and provide even more insight back to the wider organization.” – Nihar Gupta, General Manager for Data Solutions, Rackspace Technology

“We have always been looking for a unified platform that will enable both data processing and machine learning model training/scoring. Amazon Redshift has been our preferred data warehouse for processing large volumes of customer transactional data and we are increasingly leveraging Amazon SageMaker for model training and scoring. Until now, we had to move the data back and forth between the two for the ML steps in pipelines, which is quite time consuming and error prone. With the ML feature embedded, Amazon Redshift becomes that unified platform we have been looking for which will significantly simplify our ML pipelines.” – Srinivas Chilukuri, Principal – AI Center of Excellence, ZS Associates

Conclusion

In this post, we briefly discussed ML use cases relevant for data warehousing. We introduced Amazon Redshift ML and outlined how it enables SQL users to create, train, deploy, and use ML with simple SQL commands without learning external tools. We also provided an example of how to get started with Amazon Redshift ML.

Amazon Redshift ML also enables ML experts such as data scientists to quickly create ML models to simplify their pipeline and eliminate the need to export data from Amazon Redshift. We will discuss how data scientists can use Amazon Redshift ML in a future post.


About the Authors

Debu Panda, a senior product manager at AWS, is an industry leader in analytics, application platform, and database technologies and has more than 20 years of experience in the IT world.


Yannis Papakonstantinou is a senior principal scientist at AWS and professor (on leave) of University of California at San Diego whose research on querying nested and semi-structured data, data integration, and the use and maintenance of materialized views has received over 16,500 citations.


Murali Balakrishnan Narayanaswamy is a senior machine learning scientist at AWS and received a PhD from Carnegie Mellon University on the intersection of AI, optimization, learning and inference to combat uncertainty in real-world applications.


Sriram Krishnamurthy is a software development manager for the Amazon Redshift query processing team and has been working on semi-structured data processing and SQL compilation and execution for over 15 years.


Sudipta Sengupta is a senior principal technologist at AWS who leads new initiatives in AI/ML, databases, and analytics and holds a Ph.D. in electrical engineering and computer science from Massachusetts Institute of Technology.


Stefano Stefani is a VP and distinguished engineer at AWS and has served as chief technologist for Amazon DynamoDB, Amazon Redshift, Amazon Aurora, Amazon SageMaker, and other services.


How the Allen Institute uses Amazon EMR and AWS Step Functions to process extremely wide transcriptomic datasets

Post Syndicated from Gautham Acharya original https://aws.amazon.com/blogs/big-data/how-the-allen-institute-uses-amazon-emr-and-aws-step-functions-to-process-extremely-wide-transcriptomic-datasets/

This is a guest post by Gautham Acharya, Software Engineer III at the Allen Institute for Brain Science, in partnership with AWS Data Lab Solutions Architect Ranjit Rajan, and AWS Sr. Enterprise Account Executive Arif Khan.

The human brain is one of the most complex structures in the universe. Billions of neurons and trillions of connections come together to form a labyrinthine network of activity. Understanding the mechanisms that guide our minds is one of the most challenging problems in modern scientific research.

The Allen Institute for Brain Science is dedicated to solving large-scale, fundamental problems in neuroscience. Our mission is to accelerate the rate at which the world understands the inner workings of the human brain and to uncover the essence of what makes us human.

Processing extremely wide datasets

As a part of “big science,” one of our core principles, we seek to tackle scientific challenges at scales no one else has attempted before. One of these challenges is processing large-scale transcriptomic datasets. Transcriptomics is the study of RNA. In particular, we’re interested in the genes that are expressed in individual neurons. The human brain contains almost 100 billion neurons—how do they differ from each other, and what genes do they express? After a series of complex analysis using cutting-edge techniques such as Smart-Seq and 10x Genomics Chromium Sequencing, we produce extremely large matrices of numeric values.

Such matrices are called feature matrices. Each column represents the feature of a cell, which in this case are genes. A genome is over 50,000 genes, so a single matrix can have over 50,000 columns! We expect the number of rows in our matrices to increase over time, reaching tens of millions, if not more. These matrices can reach 500 GB or more in size. Over the next few years, we want to be able to ingest tens or hundreds of such matrices.

Our goal is to provide low-latency visualizations on such matrices, allowing researchers to aggregate, slice, and dissect our data in real time. To do this, we run a series of precomputations that store expensive calculations in a database for future retrieval.

We wanted to create a flexible, scalable pipeline to run computations on these matrices and store the results for visualizations.

The pipeline

We wanted to build a pipeline that takes these large matrices as inputs, runs various Spark jobs, and stores the outputs in an Apache HBase cluster. We wanted to create something flexible so that we could easily add additional Spark transformations.

We decided on AWS Step Functions as our workflow-orchestration tool of choice. Step Functions allows us to create a state machine that orchestrates the dataflow from payload submission to database loading.

After close collaboration with the engineers at the AWS Data Lab, we came up with the following pipeline architecture.

At a high level, our pipeline has the following workflow:

  1. Trigger a state machine from an upload event to an Amazon Simple Storage Service (Amazon S3) bucket.
  2. Copy and unzip the input ZIP file containing a feature matrix into an Amazon S3 working directory.
  3. Run Spark jobs on Amazon EMR to transform input feature matrices into various pre-computed datasets. Store all intermittent results in a working directory on Amazon S3 and output the results of the Spark Jobs as HFiles.
  4. Bulk load the results of our Spark jobs into Apache HBase.

The preceding architecture diagram is deceptively simple. We found a number of challenges during our initial implementation, which we discuss in the following sections.

Lack of transaction support and rollbacks across tables in Apache HBase

The results of our Spark jobs are a number of precomputed views of our original input dataset. Each view is stored as a separate table in Apache HBase. A major drawback of Apache HBase is the lack of a native transactional system. HBase only provides row-level atomicity. Our worst-case scenario is writing partial data—cases where some views are updated, but not others, showing different results for different visualizations and resulting in scientifically incorrect data!

We worked around this by rolling our own blue/green system on top of Apache HBase. We suffix each set of tables related to a dataset with a universally unique identifier (UUID). We use Amazon DynamoDB to track the UUID associated with each individual dataset. When an update to a dataset is being written, the UUID is not switched in DynamoDB until we verify that all the new tables have been successfully written to Apache HBase. We have an API on top of HBase to facilitate reads. This API checks DynamoDB for the dataset UUID before querying HBase, so user traffic is never redirected toward a new view until we confirm a successful write. Our API involves an AWS Lambda function using HappyBase to connect to our HBase cluster, wrapped in an Amazon API Gateway layer to provide a REST interface. The following diagram illustrates this architecture.

The read path has the following steps:

  • R1 – API Gateway invokes a Lambda function to fetch data from a dataset
  • R2 – The Lambda function requests and receives the dataset UUID from DynamoDB
  • R3 – Lambda queries the Apache HBase cluster with the UUID

The write path has the following steps:

  • W1 – The state machine bulk loads new dataset tables to the Apache HBase cluster suffixed with the new UUID
  • W2 – After validation, the state machine updates DynamoDB so user traffic is directed towards those changes

Stalled Spark jobs on extremely wide datasets

Although Apache Spark is a fantastic engine for running distributed compute operations, it doesn’t do too well when scaling to extremely wide datasets. We routinely operate on data that surpasses 50,000 columns, which often causes issues such as a stalled JavaToPython step in our PySpark job. Although we have more investigating to do to figure out why our Spark jobs hang on these wide datasets, we found a simple workaround in the short term—batching!

A number of our jobs involve computing simple columnar aggregations on our data. This means that each calculation on a column is completely independent of all the other columns. This lends itself quite well to batching our compute. We can break our input columns into chunks and run our compute on each chunk.

The following code chunks Apache Spark aggregation functions into groups of columns:

def get_aggregation_for_matrix_and_metadata(matrix, metadata, group_by_arg, agg_func, cols_per_write):
   '''
   Performs an aggregation on the joined matrix, aggregating the desired column by the given function.
   agg_func must be a valid Pandas UDF function. Runs in batches so we don't overload the Task Scheduler with 50,000
   columns at once.
   '''
   # Chunk the data
   for col_group in pyspark_utilities.chunks(matrix.columns, cols_per_write):

       # Add the row key to the column group
       col_group.append(matrix.columns[0])

       selected_matrix = matrix.select(pyspark_utilities.escape_column_list(col_group))

       # create argument list for group by and then process
       cast_as_udf = pyspark_functions.pandas_udf(
                       agg_func,
                       pyspark_datatype.FloatType(),
                       pyspark_functions.PandasUDFType.GROUPED_AGG)

       udf_input = [cast_as_udf(selected_matrix [column_name]).alias(column_name)
                    for column_name in selected_matrix .columns
                    if column_name != group_by_arg]

       yield joined.groupby(group_by_arg).agg(*udf_input)

We then write the results of each batch to an HFile, which is then later bulk loaded into HBase.

Because the post-aggregation DataFrame was very small, we found a significant performance increase in coalescing the DataFrame post-aggregation and checkpointing the results before writing the HFiles. This forces Spark to compute the aggregation before writing the HFiles. HFiles need to be sorted by row key, so it’s easier to pass a smaller DataFrame to our HFile converter.

Using Apache Spark to write DataFrames as HFiles

Apache Spark supports writing DataFrames in multiple formats, including as HFiles. However, the documentation for doing so leaves a lot to be desired. To write out our Spark DataFrames as HFiles, we had to take the following steps:

  1. Convert a DataFrame into a HFile-compatible format, assuming that the first column is the HBase rowkey—(row_key, column_family, col, value).
  2. Create a JAR file containing a converter to convert input Python Objects into Java key-value byte classes. This step took a lot of trial and error—we couldn’t find clear documentation on how the Python object was serialized and passed into the Java function.
  3. Call the saveAsNewAPIHadoopFile function, passing in the relevant information: the ZooKeeper Quorum IP, port, and cluster DNS of our Apache HBase on the Amazon EMR cluster; the HBase table name; the class name of our Java converter function; and more.

The following code writes HFiles:

import src.spark_transforms.pyspark_jobs.pyspark_utilities as pyspark_utilities
import src.spark_transforms.pyspark_jobs.output_handler.emr_constants as constants


def csv_to_key_value(row, sorted_cols, column_family):
   '''
   This method is an RDD mapping function that will map each
   row in an RDD to an hfile-formatted tuple for hfile creation
   (rowkey, (rowkey, columnFamily, columnQualifier, value))
   '''
   result = []
   for index, col in enumerate(sorted_cols[constants.ROW_KEY_INDEX + 1:], 1):
       row_key = str(row[constants.ROW_KEY_INDEX])
       value = row[index]

       if value is None:
           raise ValueError(f'Null value found at {row_key}, {col}')

       # We store sparse representations, dropping all zeroes.
       if value != 0:
           result.append((row_key, (row_key, column_family, col, value)))

   return tuple(result)


def get_sorted_df_by_cols(df):
   '''
   Sorts the matrix by column. Retains the row key as the initial column.
   '''
   cols = [df.columns[0]] + sorted(df.columns[1:])
   escaped_cols = pyspark_utilities.escape_column_list(cols)
   return df.select(escaped_cols)


def flat_map_to_hfile_format(df, column_family):
   '''
   Flat maps the matrix DataFrame into an RDD formatted for conversion into HFiles.
   '''
   sorted_df = get_sorted_df_by_cols(df)
   columns = sorted_df.columns
   return sorted_df.rdd.flatMap(lambda row: csv_to_key_value(row, columns, column_family)).sortByKey(True)


def write_hfiles(df, output_path, zookeeper_quorum_ip, table_name, column_family):
   '''
   This method will sort and map the medians psyspark dataFrame and
   then write to hfiles in the output directory using the supplied
   hbase configuration.
   '''
   # sort columns other than the row key (first column)

   rdd = flat_map_to_hfile_format(df, column_family)

   conf = {
           constants.HBASE_ZOOKEEPER_QUORUM: zookeeper_quorum_ip,
           constants.HBASE_ZOOKEEPER_CLIENTPORT: constants.ZOOKEEPER_CLIENTPORT,
           constants.ZOOKEEPER_ZNODE_PARENT: constants.ZOOKEEPER_PARENT,
           constants.HBASE_TABLE_NAME: table_name
           }

   rdd.saveAsNewAPIHadoopFile(output_path,
                              constants.OUTPUT_FORMAT_CLASS,
                              keyClass=constants.KEY_CLASS,
                              valueClass=constants.VALUE_CLASS,
                              keyConverter=constants.KEY_CONVERTER,
                              valueConverter=constants.VALUE_CONVERTER,
                              conf=conf)

The following code describes all the constants configuration:

HBASE_ZOOKEEPER_QUORUM="hbase.zookeeper.quorum"
HBASE_ZOOKEEPER_CLIENTPORT="hbase.zookeeper.property.clientPort"
ZOOKEEPER_ZNODE_PARENT="zookeeper.znode.parent"
HBASE_TABLE_NAME="hbase.mapreduce.hfileoutputformat.table.name"

OUTPUT_FORMAT_CLASS='org.apache.hadoop.hbase.mapreduce.HFileOutputFormat2'
KEY_CLASS='org.apache.hadoop.hbase.io.ImmutableBytesWritable'
VALUE_CLASS='org.apache.hadoop.hbase.KeyValue'
KEY_CONVERTER="org.apache.spark.examples.pythonconverters.StringToImmutableBytesWritableConverter"
VALUE_CONVERTER="KeyValueConverter"

ZOOKEEPER_CLIENTPORT='2181'
ZOOKEEPER_PARENT='/hbase'

ROW_KEY_INDEX = 0

The following code is a Java class to serialize input PySpark RDDs:

import org.apache.spark.api.python.Converter;
import org.apache.hadoop.hbase.KeyValue;
import java.util.ArrayList;
import java.util.Arrays;
import java.util.Collection;
import java.util.List;

/**
* This class is used to convert a tuple
* supplied by a spark job created in Python
* to the corresponding hbase keyValue type
* which is needed for hfile creation.
*
*/
@SuppressWarnings("rawtypes")
public class KeyValueConverter implements Converter {

  private static final long serialVersionUID = 1L;

  /**
   * this method will take a tuple object supplied
   * by Python spark job and convert and
   * return the corresponding hbase KeyValue object.
   */
  public Object convert(Object obj) {
     KeyValue cell;
     List<?> list = new ArrayList<>();
     if (obj.getClass().isArray()) {
          list = Arrays.asList((Object[])obj);
      } else if (obj instanceof Collection) {
          list = new ArrayList<>((Collection<?>)obj);
      }

     cell = new KeyValue(
           list.get(0).toString().getBytes(),
           list.get(1).toString().getBytes(),
           list.get(2).toString().getBytes(),
           list.get(3).toString().getBytes());

     return cell;
  }
}

Looking ahead

Our computation pipeline was a success, and you can see the resulting visualizations on https://transcriptomics.brain-map.org/.

We’ve been thrilled with AWS’s reliable and feature-rich ecosystem. We used Amazon EMR, Step Functions, and Amazon S3 to build a robust, large-scale data processing pipeline.

Since writing this post, we’ve done much more, including a cross-database transaction system, wide-matrix transposes in Spark, and more. Big Data problems in neuroscience never end, and we’re excited to share more with you in the future!


About the Authors

Gautham Acharya is a Software Engineer at the Allen Institute for Brain Science. He works on the backend data platform team responsible for integrating multimodal neuroscience data into a single cohesive system.


Ranjit Rajan is a Data Lab Solutions Architect with AWS. Ranjit works with AWS customers to help them design and build data and analytics applications in the cloud.


Arif Khan is a Senior Account Executive with Amazon Web Services. He works with nonprofit research customers to help shape and deliver on a strategy that focuses on customer success, building mind share and driving broad use of Amazon’s utility computing services to support their mission.

Transform data and create dashboards simply using AWS Glue DataBrew and Amazon QuickSight

Post Syndicated from Prithiviraj Jothikumar original https://aws.amazon.com/blogs/big-data/transform-data-and-create-dashboards-simply-using-aws-glue-databrew-and-amazon-quicksight/

Before you can create visuals and dashboards that convey useful information, you need to transform and prepare the underlying data. The range and complexity of data transformation steps required depends on the visuals you would like in your dashboard. Often, the data transformation process is time-consuming and highly iterative, especially when you are working with large datasets.

In this post, we show you how to apply data transformations on COVID-related tweets (with sentiment scores) using AWS Glue DataBrew. AWS Glue DataBrew’s visual and interactive interface allows us to apply data transformations without any coding. Some examples of transformations we apply are: changing date formats, transformation of text strings and performing table pivots. We then use Amazon QuickSight to visualize the transformed data in a dashboard.

See the AWS architecture diagram below for an overview of the complete and serverless data pipeline.


These are seven main steps in the data pipeline:

  1. Upload CSV file with tweets to S3
  2. Trigger AWS Lambda to partition the dataset in case the number of rows exceeds a threshold, and store the output in S3. A threshold is placed to prevent a memory exception failure to compute VADER sentiment score.
  3. Use Amazon SQS and AWS Lambda to compute VADER sentiment scores for tweets and store the VADER output as parquet files in S3
  4. Crawl the VADER output and produce a Data Catalog using AWS Glue, so that the data can be queried easily using Amazon Athena
  5. Use the Data Catalog connector in AWS Glue DataBrew to create a recipe and perform transformations
  6. Setup a Recipe job to perform the transformation and send the output to an S3 location; repeat step 5 to produce a data catalog of the transformed data
  7. Query and submit the data to Amazon QuickSight to create visuals for the dashboard

Each section below corresponds to one (or more) of the seven steps described above.

Steps 1 to 3: Setting and Deploying AWS Lambda pipeline

To test the solution we can use the AWS CloudFormation template found here. The AWS CloudFormation template automatically creates the following for you: the S3 Bucket to store the CSV and parquet files, the Lambda function to partition the files, the SQS queue and the VADER Lambda function.

Deploying the CloudFormation Template

  1. Create an S3 bucket with the name of your choice and note the bucket name. Please refer to this guide for detailed steps on how to create an S3 bucket.
  2. Upload all four individual zip files to the S3 bucket created in step 1. To do so, download the zip file from here, make sure to unzip the downloaded file and place each of the four individual zip files into the S3 bucket created in step 1.
  3. Open the AWS Management Console in the AWS Region you want to deploy the solution to, and on the Services menu, choose CloudFormation.
  4. Choose Create Stack, choose Upload a template to Amazon S3, and then choose the file databrew-cloudformation.yaml included in the solution that you downloaded earlier and if not, click on the link provided on this step to download.
  5. Set Stack name to databrew-stack. Specify the Amazon S3 bucket that contains the compressed version of AWS Lambda function code and layers uploaded in step 2.
  6. For Options, you can specify tags for your stack and an optional IAM role to be used by AWS CloudFormation to create resources. If the role isn’t specified, a new role is created. You can also perform additional configuration for rollback settings and notification options.
  7. The review section shows a recap of the information. Be sure to select the three AWS CloudFormation acknowledgements to allow AWS CloudFormation to create resources with custom names on your behalf. Also, create a change set, because the AWS CloudFormation template includes the AWS::Serverless-2016-10-31

  8. Click Execute.
  9. The Outputs for the stack lists all the resources created.

Downloading the dataset

  1. Download the dataset from here.

Testing the solution

  1. Navigate to the S3 console.
  2. Click on the bucket name (created by CloudFormation template and listed in the Outputs section of the stack).
  3. Create folder named input in the S3 bucket.
  4. Upload the downloaded dataset to the folder created in step 3.
  5. The above will trigger a lambda function to chunk the files into smaller files and proceed to another lambda function triggered by an SQS event to perform the following preprocessing steps: removal of https links, VADER sentiment scores of the 4 categories (compound, positive, negative, and neutral), and saving the file as a parquet file in S3 the path called processedv4.

Step 4: Setup AWS Glue Data Catalog

An AWS Glue Data Catalog will allows us to easily import data into AWS Glue DataBrew. Follow these steps to create a Glue crawler that crawls the the raw data with VADER output in partitioned parquet files in S3 and determines the schema:

  1. Choose a crawler name.
  2. Use the default options for Crawler source type.
  3. Provide the S3 location of the parquet files.
  4. Choose/Create an IAM role that has read/write permissions to S3 and the AWSGlueServiceRole policy attached.
  5. Set the frequency as Run on demand.
  6. Choose a database name for the crawler’s output.
  7. Leave all remaining options as default.

Once the crawler has been created, select and run the new crawler. Upon completion, the table schema is generated and visible within Tables under the Databases section in the AWS Glue console.

Step 5: Creating a DataBrew project

To get started with AWS Glue DataBrew, complete the following steps:

  1. On the DataBrew console, choose Projects.
  2. Choose Create project.
  3. For Project Name, enter covid19-tweets.
  4. For Attached recipe, choose Create new recipe.
  5. For Recipe name, enter covid19-tweets-recipe.
  6. For Select a dataset, select New dataset.
  7. For Dataset name, enter covid19-tweets-data.
  8. Import the AWS Glue table <YOUR-GLUE-TABLE-NAME> from the AWS Glue database <YOUR-GLUE-DATABASE-NAME>.
  9. Create a new AWS Identity and Access Management (IAM) policy and IAM role by following the steps on the AWS Glue DataBrew console, which provides DataBrew the necessary permissions to access Amazon S3, Amazon Athena and AWS Glue.
  10. Select Create Project.

Step 6: Data transformations, creating a AWS Glue DataBrew recipe and recipe job

Exploratory data analysis (EDA) is an essential component of the data transformation workflow. EDA allows us to gain an intuitive understanding of the dataset by summarizing its main characteristics such as the distribution of data across columns, the corresponding data types and summary statistics. For more information on EDA using AWS Glue DataBrew, see the Exploratory Data Analysis section of the post Data preprocessing for machine learning on Amazon EMR made easy with AWS Glue DataBrew.

The set of data transformation steps listed below are based on the EDA and the attributes we would like to visualize in the Amazon QuickSight dashboard.

  1. Delete the following columns user_descriptionuser_createduser_verifiedis_retweet, user_followers, user_friends, user_favourites and use_name, because the aforementioned columns are not dependent for Amazon QuickSight dashboard.

Based on the schema view of the dataset, we can observe that the date column is represented as a string. AWS Glue DataBrew provides various transformations date-time formats to convert date types.

  1. Select from the dropdown select Date functions, then DATEFORMAT.
    1. Create a new column based on the values in the source column.
    2. For source column, select date.
    3. For date format, select mm/dd/yy*HH:MM.
  2. Delete the date column and rename the date_DATEFORMAT column to date.


A visual representation of the positive, negative, neutral, and compound scores generated by the VADER AWS Lambda function is helpful to understand the sentiments of the tweets over time. Individual scores could have large variation between rows leading to large fluctuations on the line graph. We can use the rolling window transformation over observations in a column, to create a smoother, less fluctuating line graph. To apply the rolling window function, create a less granular version of the date column that is truncated of the hours and minute.

  1. Select From the dropdown select Date functions, then DATEFORMAT.
    1. Create a new column based on the values in the source column
    2. For source column, select date
    3. For date format, select mm/dd/yy to transform the observations at a date-level
    4. For destination column, enter date_level.
  2. Select From the dropdown select Window functions, then ROLLING AVERAGE.
    1. For source column, select compound
    2. Select 3 rows before and after. This is the size of the rolling window that slides over the column and impacts the smoothness of the average score from one row to another; larger window sizes produce more smoother rolling average scores and vice-versa.
    3. Order the observations by the date column because it’s granularity is at the hour- and minute-level
    4. Group the observations by the date_level column, which is only represented in date without the time
    5. For the destination column name, enter rolling_compound.

  3. Repeat step 5 above for each of the source columns pos, neu and neg to create rolling_pos, rolling_neu and rolling_neg.

To support downstream visuals in Amazon QuickSight, apply the unpivot transformation to convert the selected columns into row values.

  1. Select Pivot transformation
    1. For pivot type, select Unpivot: Columns to rows
    2. In the unpivot columns dropdown, select the columns rolling_compound, rolling_pos, rolling_neu and rolling_neg
    3. For column name, enter Rolling_category and for column value enter VADER_score

The hashtags column contains an array of hashtags. To visualize the hashtags as a word cloud in Amazon QuickSight, create a new row for each hashtag from the array by applying the unnest transformation.

  1. Select unnest
    1. For source column, select hashtags
    2. For the destination column name, enter unnest_hashtags

Normalize the data in the unnest_hashtags column

  1. Format the data in unnest_hashtags column to lowercase
  2. Remove all special characters by selecting the clean transformation

The data preparation phase is now complete, and the set of 20 transformations that consist of date formatting, rolling window functions and normalized columns are combined into a recipe.

The transformations above were applied on a sample of the first 500 rows of the dataset. AWS Glue DataBrew recipe job provides the ability to scale the set of transformation steps from a sample of data to the entire dataset.

To create a recipe job, complete the following steps:

  1. On the AWS Glue DataBrew console, choose Jobs.
  2. Choose Create recipe job.
  3. For Job name, enter a name.
  4. Create a new folder in Amazon S3 for the recipe job output, select the file type as GLUEPARQUET and compression as Snappy.

If your dataset is updated on a regular basis, AWS Glue DataBrew provides an option to schedule jobs.

To query the newly transformed data from S3 into Amazon QuickSight, create another new crawler/table in AWS Glue similar to steps provided earlier (refer to the following section: Step 4: Setup an AWS Glue Data Catalog).

Use AWS QuickSight to visualize transformed data

Before proceeding, make sure your Amazon QuickSight account has IAM permissions to access Amazon Athena and S3. Add a new dataset by clicking on Datasets from the left panel and click on New dataset. Select Athena from the list of data sources and provide a name for the Data source name and on the next section. When prompted, select the database and table that contains the table post AWS Glue DataBrew transformation and click Use custom SQL followed by changing the New custom SQL name to TableOrderedData and paste the following SQL query before selecting Edit/Preview data:

SELECT * FROM "<db>"."<table_name>" t ORDER BY t.date;

Replace <db> with your database and <table_name> with your table name. Leave the quotes in place.

Click Apply to make some further modifications.

  1. For the date column, change the data type from Stringto Date and provide the format the date as it is presented in the column (i.e. MM/dd/yy HH:mm). Similarly, change date_level column into Date
  2. Click Save and visualize to approach the next step, which is to analyze the data. In the Analyses section, select Horizontal bar chart under Visual types followed by clicking vader_score and rolling_category. Under Field wells, change vader_score (Sum) to vader_score (Average) as the Aggregate.
  3. For this visual, select Actions and select Filter same-sheet visuals under Quick create.
  4. Create another panel by selecting Add to create a line graph that allows rolling score. Select Line chart under Visual types and select the following in the presented order: vader_score, date, and rolling_category. Under Field wells, change vader_score (Sum) to vader_score (Average) as the Aggregate. Likewise, change date (Day) to date (Hour) as the Aggregate. Similar to the previous panel, create a quick action item.
  5. Further panels can also be created, such as word cloud of hashtags or a pivot table consisting of the different VADER categories with score and date. The following image is based on selecting the rolling_pos bar on the first quadrant, which filters and cascades to the rest of the panels to that of the rolling_pos filter.
  6. First quadrant depicts the overall average of each category of the entirety of the dataset. The second quadrant depicts the rolling average that is aggregated by the hour. The third quadrant is table representative that is depicted as the rolling average that is aggregated by the day. The word cloud panel is from the hashtags column.

Summary

In this post, we showed you how to interactively analyze and visualize a dataset using AWS Lambda, AWS Glue Databrew and Amazon QuickSight. We began with a COVID19 tweets dataset and computed their sentiment scores using the VADER algorithm. We then cleaned and prepared the tweets and their sentiment scores in AWS Glue DataBrew, and finally visualized key characteristics of the dataset in Amazon QuickSight.

We encourage you to extend this pipeline to your data analytics + visualization use case – there are many more pre-built transformations in AWS Glue DataBrew and pre-built visuals in Amazon QuickSight to explore.

Happy Building!


About the Authors

Prithiviraj Jothikumar, PhD, is a Data Scientist with AWS Professional Services, where he helps customers build solutions using machine learning. He enjoys watching movies and sports and spending time to meditate.


Kartik Kannapur is a Data Scientist with AWS Professional Services. He holds a Master’s degree in Applied Mathematics and Statistics from Stony Brook University and focuses on using machine learning to solve customer business problems.


Bala Krishnamoorthy is a Data Scientist with AWS Professional Services, where he helps customers solve problems and run machine learning workloads on AWS. He has worked with customers across diverse industries, including software, finance, and healthcare. In his free time, he enjoys spending time outdoors, running with his dog, beating his family and friends at board games and keeping up with the stock market.


Paritosh Walvekar is a Cloud Application Architect with AWS Professional Services, where he helps customer build cloud native applications. He has a Master’s degree in Computer Science from University at Buffalo. In his free time, he enjoys watching movies and is learning to play the piano.


Amazon EMR now provides up to 30% lower cost and up to 15% improved performance for Spark workloads on Graviton2-based instances

Post Syndicated from Peter Gvozdjak original https://aws.amazon.com/blogs/big-data/amazon-emr-now-provides-up-to-30-lower-cost-and-up-to-15-improved-performance-for-spark-workloads-on-graviton2-based-instances/

Amazon EMR now supports M6g, C6g and R6g instances with Amazon EMR versions 6.1.0, 5.31.0 and later. These instances are powered by AWS Graviton2 processors that are custom designed by AWS using 64-bit Arm Neoverse cores to deliver the best price performance for cloud workloads running in Amazon Elastic Compute Cloud (Amazon EC2). On Graviton2 instances, Amazon EMR runtime for Apache Spark provides up to 15% improved performance at up to 30% lower costs relative to equivalent previous generation instances. In our TPC-DS 3 TB benchmark tests, we found that queries run up to 32 times faster using Amazon EMR runtime for Apache Spark. For more information, see Amazon EMR introduces EMR runtime for Apache Spark.

You can use Apache Spark for a wide array of analytics use cases ranging from large-scale transformations to streaming, data science, and machine learning. Amazon EMR provides the latest, stable, open-source innovations, performant storage with Amazon S3, and the unique cost savings capabilities of Spot Instances and Managed Scaling.

Amazon EMR runtime for Apache Spark is a performance-optimized runtime environment for Apache Spark, available and turned on by default on Amazon EMR release 5.28.0 and later. Amazon EMR runtime for Apache Spark provides 100% API compatibility with open-source Apache Spark. This means that your Apache Spark workloads run faster and incur lower compute costs when run on Amazon EMR without requiring any changes to your application.

In this post, we discuss the results that we observed by running Spark workloads on Graviton2 instances.

AWS Graviton2 and Amazon EMR runtime performance improvements

To measure improvements, we ran TPC-DS 3 TB benchmark queries on Amazon EMR 5.30.1 using Amazon EMR runtime for Apache Spark (compatible with Apache Spark version 2.4) with 5-10 node clusters of M6g instances with data in Amazon Simple Storage Service (Amazon S3) and compared it to equivalent configuration using M5 instances. We measured performance improvements using total query execution time and geometric mean of query execution time across the 104 TPC-DS 3 TB benchmark queries.

The results showed improved performance on M6g instance EMR clusters compared to equivalent M5 instance EMR clusters of between 11.61–15.61% improvement in total query runtime for different sizes within the instance family, and between 10.52–12.91% improvement in geometric mean. To measure cost improvement, we added up the Amazon EMR and Amazon EC2 cost per instance per hour and multiplied it by the total query runtime. We observed between 21.58–30.58% reduced instance hour cost on M6g instance EMR clusters compared equivalent M5 instance EMR clusters to execute the 104 TPC-DS benchmark queries.

The following table shows results from running TPC-DS 3 TB benchmark queries using Amazon EMR 5.30.1 over equivalent M5 and M6g instance EMR clusters.

Instance Size 16 XL 12 XL 8 XL 4 XL 2 XL
Number of core instances in EMR cluster 5 5 5 5 10
Total query runtime on M5 (seconds) 6157 6167 6857 10593 10676
Total query runtime on M6g (seconds) 5196 5389 6061 9313 9240
Total query execution time improvement with M6g 15.61% 12.63% 11.61% 12.08% 13.45%
Geometric mean query execution time on M5 (sec) 33 34 35 47 47
Geometric mean query execution time on M6g (sec) 29 30 32 41 42
Geometric mean query execution time improvement with M6g 12.73% 10.79% 10.52% 12.91% 11.24%
EC2 M5 instance price ($ per hour) $3.072 $2.304 $1.536 0.768 0.384
EMR M5 instance price ($ per hour) $0.27 $0.27 $0.27 0.192 0.096
(EC2 + EMR) M5 instance price ($ per hour) $3.342 $2.574 $1.806 $0.960 $0.480
Cost of running on M5 ($ per instance) $5.72 $4.41 $3.44 $2.82 $1.42
EC2 M6g instance price ($ per hour) $2.464 $1.848 $1.232 $0.616 $0.308
EMR M6g price ($ per hour per instance) $0.616 $0.462 $0.308 $0.15 $0.08
(EC2 + EMR) M6g instance price ($ per hour) $3.080 $2.310 $1.540 $0.770 $0.385
Cost of running on M6g ($ per instance) $4.45 $3.46 $2.59 $1.99 $0.99
Total cost reduction with M6g including performance improvement -22.22% -21.58% -24.63% -29.48% -30.58%

The following graph shows per query improvements observed on M6g 2XL instances with EMR Runtime for Spark on Amazon EMR version 5.30.1 compared to equivalent M5 2XL instances for the 104 queries in the TPC-DS 3 TB benchmark. Performance of 100 of 104 TPC-DS queries improved with M6g 2XL, and performance for 4 queries regressed (q41, q20, q42, and q52 – with the maximum regression of -20.99%). If you are evaluating migrating from M5 instances to M6g instances for EMR Spark workloads, we recommend that you test your workloads to check if any of your queries encounter slower performance.


R6g instances showed a similar performance improvement while running Apache Spark workloads compared to equivalent R5 instances. Our test results showed between 14.27-21.50% improvement in total query runtime for 5 different instance sizes within the instance family, and between 12.48-18.95% improvement in geometric mean. On cost comparison, we observed 23.26%-31.66% reduced instance hour cost on R6g instance EMR clusters compared to R5 EMR instance clusters to execute the 104 TPC-DS benchmark queries. We observed 4 benchmark queries (q6, q21, q41 and q26 – with a maximum regression of -18.28%) taking longer to execute on R6g instance clusters compared to R5 instance clusters.

With C6g instances, we observed improved performance compared to C5 instances for Spark workloads on 2XL, 4XL, 12XL and 16XL instance sizes. Query execution performance regressed on 8XL instances by -0.38%. We observed between 16.84-24.15% lower instance hour costs on C6g instance EMR clusters compared equivalent C5 EMR instance clusters to execute the 104 TPC-DS benchmark queries. Performance of 73 of 104 TPC-DS queries improved with C6g 4XL, and performance for 31 queries regressed (with a maximum regression of -31.38% for q78).

Summary

By using Amazon EMR with M6g, C6g and R6g instances powered by Graviton2 processors, we observed improved performance and reduced cost of running 104 TPC-DS benchmark queries. To keep up to date, subscribe to the Big Data blog’s RSS feed to learn about more Apache Spark optimizations, configuration best practices, and tuning advice.


About the Authors

Peter Gvozdjak is a senior engineering manager for EMR at Amazon Web Services.


Al MS is a product manager for Amazon EMR at Amazon Web Services.