Tag Archives: AWS CloudFormation

From clickops to governed IaC: CloudFormation drift detection in practice

Post Syndicated from Leen Alattas original https://aws.amazon.com/blogs/devops/from-clickops-to-governed-iac-cloudformation-drift-detection-in-practice/

AWS environments that have grown organically over time often share a common characteristic: infrastructure provisioned through the AWS Management Console, SDKs, or CLI without corresponding Infrastructure as Code (IaC) templates. This practice is commonly referred to as “ClickOps,” a term describing any infrastructure change made outside of a codified, version-controlled workflow. Whether changes happen through the console, the AWS CLI, or application SDKs, the result is the same: resources exist without a declarative template to describe their intended state. 

Over time, these manual changes accumulate, creating environments where Amazon Virtual Private Cloud (Amazon VPC) configurations, Amazon Elastic Compute Cloud (Amazon EC2) instances, and Amazon Simple Storage Service (Amazon S3) buckets exist without a single AWS CloudFormation template to describe them. 

Organizations that find themselves in this position have a clear opportunity. CloudFormation’s IaC Generator provides a practical starting point for bringing existing infrastructure under declarative management. It scans an AWS account and produces CloudFormation templates from existing resources, solving the first and most fundamental challenge: you cannot govern infrastructure you cannot see. 

However, generating a template is only the beginning. What follows is the operational thinking behind turning a generated template into something a team can govern and automate: the decisions, trade-offs, and organizational habits that determine whether IaC adoption succeeds long-term. 

IaC Generator: making the invisible visible 

CloudFormation’s IaC Generator scans an AWS account and produces CloudFormation templates from existing resources: Amazon VPCs, subnets, Amazon EC2 instances, Amazon S3 buckets, AWS Identity and Access Management (IAM) roles, and more. It solves the foundational problem of any ClickOps-to-IaC migration: establishing visibility into what exists and how it is configured. 

How it works at a high level 

Scan — IaC Generator discovers resources in the account by querying AWS Cloud Control API, identifying what exists regardless of how it was provisioned. 

Generate — It produces CloudFormation templates that represent the current state of those resources, mapping properties, dependencies, and relationships. 

Review — Teams evaluate the generated templates, reconcile any gaps, and decide how to bring each resource under management. 

This process eliminates weeks of manual documentation work. Instead of engineers mapping infrastructure by hand, IaC Generator produces a baseline in minutes. For a team managing 200+ resources across multiple VPCs, this can compress a multi-sprint effort into a single planning session. 

Understanding what the generator produces 

The generated templates capture the current state of resources, including every manual configuration and accumulated change. Before acting on a generated template, teams should understand what it represents and what it does not. 

Important: IaC Generator does not cover all resource types supported by CloudFormation. Before committing to an import path for any resource, verify that the resource type is supported. Coverage continues to expand, but teams should confirm support for their specific resource types before planning their migration approach. 

The generated template provides an inventory of infrastructure and surfaces implicit dependencies that were never documented. However, a template in a repository does not prevent out-of-band changes, enforce review processes, or protect against drift. Visibility is the prerequisite for control, not a substitute for it. 

Import or recreate: making the right decision for each resource 

When bringing existing resources under CloudFormation management, teams must decide on a per-resource basis whether to import a resource into a stack or to recreate it cleanly. The right choice depends on the specific characteristics of each resource: its criticality, how much operational disruption is acceptable, the complexity of its dependencies, and the technical limitations of the tooling. CloudFormation does not support partial adoption of an existing resource: a resource is either fully imported into a stack or newly provisioned through a stack. This is what makes the decision binary and per-resource rather than incremental. 

A note on configuration drift in this context: configuration drift occurs when the actual state of a resource diverges from what is defined in a template. A resource that was provisioned manually may be in a perfectly valid operational state, but it has no template against which to measure compliance. The goal of importing is to establish that baseline, not to imply the current configuration is inherently flawed.

Factor  Import existing resource  Recreate with new stack 
Resource criticality  High: production, live data, tight dependencies  Lower: dev/test, stateless, easily replaceable 
Manual changes  Significant: many out-of-band modifications  Minimal: resource is close to desired state 
Downtime tolerance  Zero: any interruption is unacceptable  Acceptable: brief maintenance window tolerable 
Template fidelity  Lower: generated template may be imperfect  Higher: full control over the final template 
Dependency complexity  High: cross-service dependencies difficult to isolate  Lower: resource can be isolated and rebuilt cleanly 

Technical limitations to consider 

Beyond operational factors, the IaC Generator has technical constraints that should inform the import-versus-recreate decision: 

  • Resource type coverage: Not all resource types supported by CloudFormation are supported by IaC Generator. Before committing to an import path, verify that the specific resource types are supported. If a critical resource type is not covered, the template must be written manually. 
  • Write-only properties: Some resource properties (such as passwords or secrets) are write-only and cannot be read back during scanning. Generated templates show placeholder values for these, requiring manual reconciliation. In production environments, this may require integration with AWS Secrets Manager or a similar secrets management solution. 
  • Hard-coded values: Generated templates produce literal values rather than parameterized inputs. Plan for a refactoring pass to introduce parameters, mappings, and conditions. 
  • Cross-account and cross-region references: IaC Generator operates within a single account and region. Resources with dependencies spanning accounts or regions require additional manual template work. 

For production resources, stateful workloads, and resources with complex dependency graphs, import is generally the appropriate default. The import operation brings resources under CloudFormation management without recreating them, preserving their current state. The trade-off is that the generated template becomes the starting point, and teams must reconcile any gaps between that template and actual resource state before making subsequent changes. 

Recreation is more appropriate when a resource can tolerate a brief maintenance window, when accumulated manual changes make a clean start more efficient than reconciliation, or when the architecture is being redesigned as part of the migration. 

The most effective approach is to segment the inventory by resource type, criticality, and configuration complexity, then match the strategy to each segment. An Amazon VPC that has been modified extensively over three years presents a different challenge than an Amazon S3 bucket created last month. 

Organizing stacks for operational reality 

A common challenge after bringing resources under CloudFormation management is determining the appropriate stack boundaries. Placing all resources into a single monolithic stack creates operational risk: changes to VPC and subnet infrastructure can inadvertently affect application resources, a rollback on an application deployment can revert infrastructure changes, and accountability becomes diffuse. When ownership is unclear, incident response slows. 

Organizing stacks around lifecycle, ownership, and change frequency addresses this challenge. The key principle is to group resources that share the same rate of change and the same responsible team: 

When these criteria conflict, ownership takes precedence: a shared resource should reside in the stack owned by its primary responsible team, with cross-stack references providing access to consuming teams. 

  • VPC and subnet infrastructure changes infrequently and is typically managed by a platform or infrastructure team. 
  • Application infrastructure changes frequently and is managed by the application teams that deploy to it. 
  • Security controls warrant their own stacks under security team ownership, insulated from application deployment cycles. 

Cross-stack references, through CloudFormation exports and imports, preserve these boundaries while maintaining relationships between stacks. A VPC stack exports Amazon VPC and subnet IDs; application stacks import them. This separation means that application deployments do not modify network configuration, and VPC or subnet changes do not require redeploying application stacks. 

Note: this separation does not eliminate all cross-cutting concerns. Changes to security groups or network ACLs, for example, may still require coordination with application teams. The goal is to reduce unintended coupling, not to eliminate all interdependency. 

This structure makes governance at scale tractable. When stacks have clear boundaries and named owners, drift detection becomes actionable. Teams know exactly who owns a drifted resource and who needs to respond. 

Drift detection: moving from reactive to continuous 

Defining drift: Configuration drift occurs when the actual state of a resource diverges from what is declared in its CloudFormation template. Drift can originate from manual console changes, AWS CLI or SDK operations, automated processes that modify resources outside of CloudFormation, or any action that bypasses the IaC workflow. Drift is not inherently a failure; it often reflects legitimate operational decisions made under time pressure. The challenge is maintaining awareness of these changes so they can be evaluated and reconciled deliberately. 

CloudFormation’s native drift detection tells teams whether resources match their templates. What it cannot do on its own is provide continuous monitoring. Manual, on-demand checks are valuable, but they are reactive. By the time a team runs one, the drift may have already caused a downstream issue. 

Automating drift detection with Amazon EventBridge 

Continuous drift detection requires three capabilities: scheduled detection runs, event capture when drift is found, and routing of alerts to the appropriate team. Amazon EventBridge provides the orchestration layer that connects these capabilities: 

  • Schedule drift detection: Configure an EventBridge rule with a cron expression to trigger the DetectStackDrift API on critical stacks at regular intervals (for example, every 6 hours for production stacks, daily for non-production). This is a custom configuration, not a built-in default; teams define the schedule based on their operational requirements. 
  • Capture drift events: CloudFormation emits events to the default EventBridge event bus when drift detection completes. Create rules that filter for CloudFormation Stack Drift Detection Status Change events where the drift status is DRIFTED. 
  • Automated remediation (with caution): For well-understood, low-risk drift patterns in non-production environments, EventBridge can trigger an AWS Lambda function that applies a drift-aware change set. However, automated remediation in production environments requires careful consideration. See the guidance below on remediation policy. 

Remediation policy: a deliberate decision 

Whether drift triggers a notification or an automated correction should be a deliberate, documented policy decision. Several factors argue for caution with automated rollbacks: 

  • Drift is typically detected well after it occurred. The change was not random; a person or process determined it was necessary at the time. 
  • Automatically reverting a change without understanding why it was made can reintroduce the problem it was intended to solve. 
  • In production environments, the safest default is to alert the owning team and let them evaluate whether the drift should be reconciled into the template or reverted. 

Automated remediation is most appropriate in controlled environments (development, staging) or for narrowly-scoped, well-understood drift patterns where the risk of unintended consequences is minimal. 

Drift-aware change sets 

Drift-aware change sets extend drift awareness into the deployment pipeline. Before applying changes, a drift-aware change set evaluates the actual current state of a stack rather than the last known state. This is critical when someone made a manual change under operational pressure but has not yet reconciled it. A routine deployment should not silently overwrite a deliberate operational decision. 

This capability supports the position that drift should generally be reconciled deliberately rather than reverted automatically. When a drift-aware change set reveals unexpected state, the deploying team can pause, investigate, and decide whether to incorporate the drift into the template or proceed with the planned change. 

Over time, drift data provides organizational insight beyond individual resource compliance. The same resource drifting repeatedly, or the same team consistently making out-of-band changes, points to gaps in process, tooling, or team capacity. That signal is valuable only if someone is reviewing it systematically. 

The operational maturity journey 

Moving from ClickOps to fully governed CloudFormation management is not a single migration event. The progression moves through four recognizable stages: 


Level  Stage  What it means 
Level 1  Visibility  The team knows what exists. IaC Generator provides templates that represent the infrastructure. Necessary, but not sufficient. 
Level 2  Control  Resources are under CloudFormation management. Changes route through templates and change sets. Drift is detectable. 
Level 3  Automation  Drift detection runs on schedule. CI/CD pipelines incorporate drift awareness. Governance is a property of the deployment process. 
Level 4  Governance  Compliance policies are enforced automatically. Drift outside defined parameters triggers remediation or escalation. Infrastructure state is continuously validated against policy. 

Moving from visibility to control is primarily an organizational challenge. It requires three deliberate shifts: 

  1. Ownership

Every CloudFormation stack needs a named team responsible for its drift state. Establish this accountability through: 

  • A mandatory team-owner tag applied to every stack. 
  • Integration with AWS Service Catalog to enforce ownership metadata from provisioning onward. 
  1. Process

Changes need to be routed through CloudFormation, not around it. Any change made outside of the IaC workflow (whether through the console, CLI, or SDK) is a potential source of drift. Governance controls include: 

  • AWS CloudTrail with EventBridge rules that flag API calls made outside of CloudFormation. 
  • A defined reconciliation window (for example, 24 hours for production hotfixes) that acknowledges operational reality while maintaining accountability. 
  1. Feedback loops

Point-in-time drift snapshots are useful, but trends over time are more valuable for identifying systemic issues. Build feedback mechanisms that surface patterns: 

  • Use Amazon Athena to query historical drift data for recurring patterns. 
  • Feed drift metrics into existing operational review cadences. 

Conclusion 

IaC Generator makes the invisible visible. It turns infrastructure provisioned outside of IaC workflows into CloudFormation templates that can be versioned, reviewed, and automated. The template is not the destination; it is the starting point for building infrastructure that teams can change with confidence and govern at scale. 

The real work is organizational: assigning stack ownership, routing changes through CloudFormation, building continuous drift awareness, and treating drift data as a signal about process gaps rather than as a compliance checkbox. Organizations that approach this as a cultural shift alongside a technical migration are the ones that sustain the gains long-term. 

Getting started 

For teams ready to implement this approach, the following resources provide step-by-step guidance: 

  • Implement drift notification routing: Use AWS Chatbot with EventBridge to route alerts to team channels, or trigger ticket creation via AWS Lambda. 

Leen AlAttas is a Technical Account Manager in the AWS Enterprise Support organization based in Riyadh, Saudi Arabia, where she has spent the past year helping enterprise customers optimize their cloud operations. She specializes in security and works closely with organizations to strengthen their AWS security posture. 

John Chebib is a Senior Technical Account Manager at AWS based out of Bahrain. He works with customers providing technical assistance and architectural guidance on various AWS services. He brings several years of experience in data analytics and architectural roles for various large-scale enterprises.
Accelerate CloudFormation development with the IaC MCP Server

Post Syndicated from Shuto Yukawa original https://aws.amazon.com/blogs/devops/accelerate-cloudformation-development-with-the-iac-mcp-server/

Organizations adopt Infrastructure as Code (IaC) to manage cloud environments reliably, repeatably, and at scale. As teams grow and infrastructure complexity increases, IaC becomes the backbone of consistent deployments, compliance enforcement, and operational agility. The developer’s experience around IaC, however, remains fragmented — engineers routinely context-switch between documentation portals, linting tools, deployment consoles, and logging systems just to complete a single deploy cycle. This friction compounds across teams: slower iteration means delayed feature releases, longer incident recovery times, and increased operational risk. When a deployment fails, diagnosing the root cause across disconnected interfaces can take longer than writing the template itself — turning a feedback loop that could take hours of manual investigation into a more streamlined process.

The AWS Infrastructure as Code (IaC) MCP Server brings AWS CloudFormation documentation search, template validation, and deployment troubleshooting into your AI assistant, so you can move through a full AWS CloudFormation development cycle without leaving the chat interface. Developing AWS CloudFormation templates often means switching between documentation pages, linters, the deployment console, and AWS CloudTrail Logs. Each context switch adds friction to the inner development loop — the tight cycle of writing, validating, deploying, and fixing infrastructure code. This fragmented workflow increases time-to-deployment, delays feedback, and reduces developer productivity, particularly for teams managing complex, multi-resource stacks at scale.

The AWS Infrastructure as Code (IaC) Model Context Protocol (MCP) Server unifies these capabilities in one place. This post demonstrates how the IaC MCP Server tools work together in a real workflow — from authoring and validation through deployment and runtime troubleshooting — all within a single AI assistant conversation.

In this post, you can move through a complete CloudFormation development cycle using your AI assistant. You generate a template for an Amazon Simple Storage Service (Amazon S3) bucket, an AWS Lambda function, an AWS Identity and Access Management (IAM) execution role, and an Amazon CloudWatch Logs log group. You then validate, deploy, diagnose a deployment failure, and redeploy, all in a single interface.

Solution overview

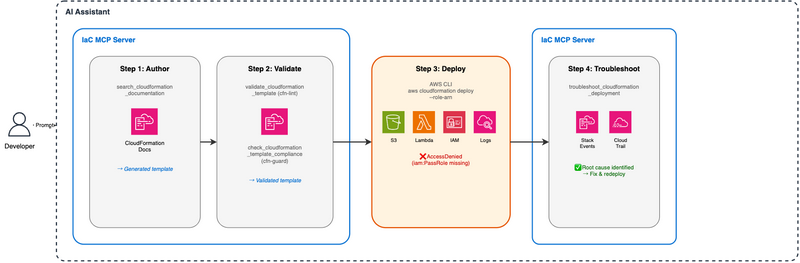
The walkthrough follows four steps that map to IaC MCP Server tools:

  1. Author: Search CloudFormation documentation and generate a template
  2. Validate: Check syntax with cfn-lint and compliance with cfn-guard
  3. Deploy: Deploy the stack using a CloudFormation service role
  4. Troubleshoot: Diagnose a deployment failure using CloudTrail correlation

Figure 1 shows the four-step workflow. Steps 1, 2, and 4 run inside the IaC MCP Server, while Step 3 uses the AWS CLI directly.

Architecture diagram showing the end-to-end CloudFormation workflow. You send a prompt to your AI assistant. Inside the AI assistant, the IaC MCP Server handles Step 1 (Author using search_cloudformation_documentation), Step 2 (Validate using cfn-lint and cfn-guard), and Step 4 (Troubleshoot using stack events and CloudTrail). Step 3 (Deploy) runs outside the IaC MCP Server using the AWS CLI with a CloudFormation service role.

Figure 1. End-to-end CloudFormation workflow with the IaC MCP Server

In the prerequisites, you deploy a CloudFormation service role stack that deliberately omits the iam:PassRole permission. During the walkthrough, you use the AI assistant to generate and deploy an application stack. When CloudFormation tries to assign the Lambda execution role, the deployment fails with AccessDenied. The troubleshoot tool then correlates stack events with CloudTrail to pinpoint the root cause.

For an introduction to each IaC MCP Server tool, see Introducing the AWS Infrastructure as Code MCP Server.

Prerequisites

Before you start the walkthrough, set up your AWS account and AI assistant and deploy the service role stack that the walkthrough depends on.

To follow along, you need:

This walkthrough uses the us-east-1 Region. You can use a different Region, but make sure to use the same Region consistently across each step.

Clone the companion repository and deploy the service role stack:

git clone https://github.com/aws-samples/sample-accelerate-cloudformation-with-iac-mcp-server.git

cd sample-accelerate-cloudformation-with-iac-mcp-server

aws cloudformation deploy \
  --template-file iac-mcp-blog-role-stack.yaml \
  --stack-name iac-mcp-blog-role-stack \
  --capabilities CAPABILITY_NAMED_IAM

This role grants CloudFormation permission to create S3 buckets, Lambda functions, and CloudWatch Logs log groups, but deliberately omits iam:PassRole — you’ll diagnose this gap in Step 4.

You use the --capabilities CAPABILITY_NAMED_IAM flag to acknowledge that the stack creates IAM resources with custom names.

We provide this role template for demonstration purposes only and do not intend it for production use.

Note the role ARN from the stack outputs. You must use this ARN in Step 3:

aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text

Walkthrough

The four steps that follow map to IaC MCP Server tools: authoring with documentation search, validating with cfn-lint and cfn-guard, deploying with a CloudFormation service role, and troubleshooting with CloudTrail correlation.

Step 1: Generate a CloudFormation template

Start by asking your AI assistant to search CloudFormation documentation and generate a template. The IaC MCP Server calls the search_cloudformation_documentation tool behind the scenes to retrieve up-to-date resource property references.

Prompt:

Create a CloudFormation template with an S3 bucket, a Lambda function (Python 3.13 runtime, inline hello-world code), an IAM execution role for the function, and a CloudWatch Logs log group. Include common security configurations. Save it as iac-mcp-blog-app-stack.yaml in the current directory.

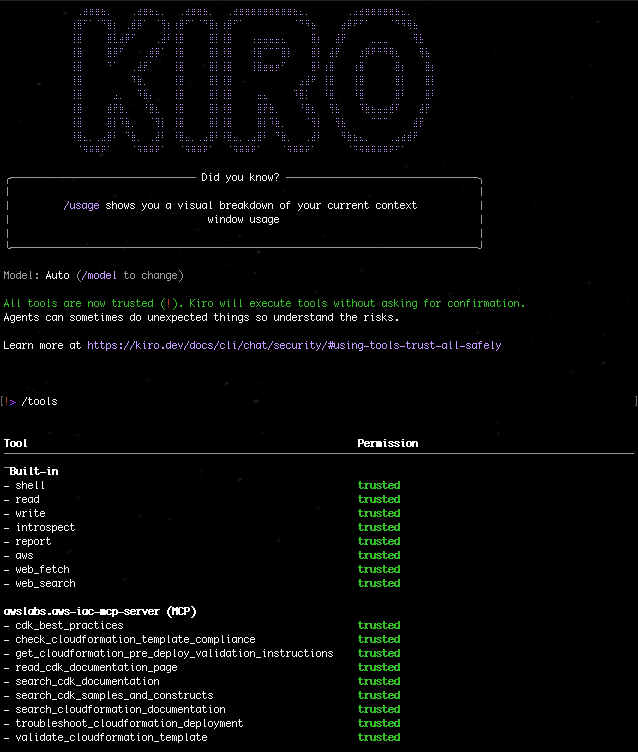
The AI assistant calls the search_cloudformation_documentation tool to look up resource properties for AWS::S3::Bucket, AWS::Lambda::Function, AWS::IAM::Role, and AWS::Logs::LogGroup. You can see the tool invocations in Kiro’s chat interface. The search results include up-to-date property references and example configurations, which the AI assistant uses to generate a template.

The generated template should include resources similar to the following (your output may vary):

  • An S3 bucket with versioning, encryption, and public access block
  • A Lambda function with inline Python code
  • An IAM role with a least-privilege policy for CloudWatch Logs
  • A log group with a retention policy

The following snippet shows the key resources. Your AI assistant’s output may differ in naming or structure, but the core configuration should be similar:

Resources:
  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      BucketEncryption:
        ServerSideEncryptionConfiguration:
          - ServerSideEncryptionByDefault:
              SSEAlgorithm: AES256
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        BlockPublicPolicy: true
        IgnorePublicAcls: true
        RestrictPublicBuckets: true
      VersioningConfiguration:
        Status: Enabled

  LambdaFunction:
    Type: AWS::Lambda::Function
    Properties:
      Runtime: python3.13
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          def handler(event, context):
              return {"statusCode": 200, "body": "Hello from Lambda!"}

Step 2: Validate the template

Before deploying, ask the AI assistant to validate the template. The IaC MCP Server provides two validation tools that wrap open source checkers: cfn-lint for syntax validation and cfn-guard for policy-as-code compliance checks.

Prompt:

Validate iac-mcp-blog-app-stack.yaml for syntax errors and compliance violations.

The AI assistant runs two checks:

  1. Syntax validation (validate_cloudformation_template): Uses cfn-lint to catch structural errors, invalid property names, and schema violations.
  2. Compliance check (check_cloudformation_template_compliance): Uses cfn-guard to evaluate the template against security rules such as S3 bucket encryption, public access block settings, and log group retention.

If either check reports issues, ask the AI assistant to fix them. Continue iterating until both checks pass.

Note that the compliance check might flag violations related to S3 object lock, access logging, replication, and inline IAM policies. For a production workload, you would address each of these issues. In this walkthrough, the AI assistant resolves them to demonstrate the iterative validate-and-fix workflow. Your results might vary depending on the template the AI assistant generated in Step 1.

After the AI assistant resolves the violations, the S3 bucket resource gains access logging and object lock properties. The following snippet shows the typical shape of these additions (see iac-mcp-blog-app-stack-fixed.yaml in the companion repository for the complete hardened template):

  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      # ... existing properties ...
      LoggingConfiguration:
        DestinationBucketName: !Ref S3LoggingBucket
        LogFilePrefix: access-logs/
      ObjectLockEnabled: true
      ObjectLockConfiguration:
        ObjectLockEnabled: Enabled
        Rule:
          DefaultRetention:
            Mode: GOVERNANCE
            Days: 30

Your template now passes both cfn-lint and cfn-guard checks. These security improvements improve your template’s security posture but are unrelated to the deployment failure you’ll encounter next. The failure in Step 3 is caused by missing permission on the service role, not by anything in the template itself.

Step 3: Deploy the stack

With validation complete, deploy the template. This deployment will fail — not because of a template error, but because the CloudFormation service role deployed in the prerequisites is missing iam:PassRole. This is the scenario you’ll diagnose in Step 4.

Now deploy the validated template using the service role you created in the prerequisites:

Prompt:

Deploy iac-mcp-blog-app-stack.yaml as a stack named “iac-mcp-blog-app-stack” in us-east-1 using the service role ARN from iac-mcp-blog-role-stack.

The AI assistant runs the AWS CLI deployment command for you. If your AI assistant doesn’t support running shell commands directly, you can deploy manually with the AWS CLI:

Manual CLI deployment

ROLE_ARN=$(aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text)

aws cloudformation deploy \
  --template-file iac-mcp-blog-app-stack.yaml \
  --stack-name iac-mcp-blog-app-stack \
  --role-arn $ROLE_ARN \
  --capabilities CAPABILITY_NAMED_IAM

The deployment fails. The stack event shows an AccessDenied error on the IAM role resource, but doesn’t identify which permission on the CloudFormation service role is missing or why. At this point, we move from static analysis to runtime troubleshooting.

Step 4: Troubleshoot the failure

Ask the AI assistant to diagnose the failure:

⚠ Note: CloudTrail events typically take 5–15 minutes to appear. Wait at least 5 minutes after the deployment failure before running the troubleshoot tool for the most complete analysis.
Prompt:

Troubleshoot the failed deployment of iac-mcp-blog-app-stack in us-east-1.

The AI assistant calls troubleshoot_cloudformation_deployment, which:

  1. Retrieves the stack events and identifies the failed resources
  2. Correlates the failure timestamps with CloudTrail API calls
  3. Identifies AccessDenied errors and the missing permissions that caused them

The troubleshoot tool identifies that the CloudFormation service role is missing iam:PassRole — the permission required to assign the Lambda execution role to the function. If your template includes the cfn-guard hardening from Step 2 (access logging, object lock), the tool may also surface additional missing S3 permissions such as s3:PutBucketObjectLockConfiguration for the logging bucket.

Prompt:

Fix iac-mcp-blog-role-stack.yaml to add the missing permissions identified by the troubleshoot tool. Save it as iac-mcp-blog-role-stack-fixed.yaml.

The AI assistant adds the missing permissions to the service role template. Now ask the AI assistant to deploy the fix, delete the failed stack, and redeploy:

Prompt:

Deploy iac-mcp-blog-role-stack-fixed.yaml to update iac-mcp-blog-role-stack, then delete the failed iac-mcp-blog-app-stack and redeploy it with the same service role.

The AI assistant runs the necessary CLI commands: updating the role stack, deleting the failed application stack, and redeploying the application stack. The failed stack is in ROLLBACK_COMPLETE state, a terminal state that CloudFormation cannot update in place, so you must delete it before redeploying.

The stack deployment succeeded.

Cost considerations

For information about costs associated with the resources in this walkthrough, including S3 storage, Lambda invocations, CloudWatch Logs, and CloudFormation operations, see AWS Pricing. Confirm that your account usage falls within any applicable free tier limits. If you enabled S3 access logging or object lock through the validation-and-fix workflow in Step 2, the logging bucket stores a small amount of access log data that falls under S3 standard pricing. See AWS Pricing for current rates and confirm that your account is within the Free Tier limits before you deploy.

Cleaning up

To avoid ongoing charges, delete both stacks.

Option A: Clean up with your AI assistant

Ask your AI assistant to run the cleanup for you. The IaC MCP Server lets the AI assistant inspect stack outputs, empty buckets, and delete both stacks in the correct order:

Clean up the iac-mcp-blog-app-stack and iac-mcp-blog-role-stack stacks in us-east-1. Empty any S3 buckets they created (including access log buckets) before deleting the application stack, then delete the role stack.

Option B: Clean up manually

Delete the application stack first because it was deployed with the service role:

⚠ Warning: If your template included access logging, the logging bucket may contain objects. CloudFormation cannot delete a non-empty bucket. Empty it first:

aws s3 rm s3://<logging-bucket-name> --recursive

Then proceed with stack deletion.

aws cloudformation delete-stack --stack-name iac-mcp-blog-app-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-app-stack

aws cloudformation delete-stack --stack-name iac-mcp-blog-role-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-role-stack

If any S3 bucket was created with DeletionPolicy: Retain or still contains objects (for example, server access logs), CloudFormation leaves it in place. Empty and delete those buckets from the S3 console or with aws s3 rb s3://<bucket-name> --force.

Next steps

If you manage CloudFormation infrastructure and find yourself losing time to context-switching between docs, linters, consoles, and logs, here’s how to streamline your workflow starting today:

  1. Set up the IaC MCP Server — Install and configure the IaC MCP Server with an MCP-compatible AI assistant such as Kiro to bring documentation search, validation, and troubleshooting into a single conversational interface.
  2. Run the walkthrough end-to-end — Clone the companion repository and follow this post step by step to experience the full author-validate-deploy-troubleshoot loop in your own AWS account.
  3. Integrate into your team’s workflow — Replace manual context-switching by embedding the IaC MCP Server’s tools into your day-to-day CloudFormation development process, reducing iteration time from hours to minutes.
  4. Extend to AWS CDK — Apply the same conversational workflow to CDK-based infrastructure using the IaC MCP Server’s CDK capabilities described in the introductory blog post.
  5. Contribute and share feedback — Report issues or suggest enhancements on the AWS MCP GitHub repository to help shape future capabilities.

Conclusion

In this walkthrough, you used the IaC MCP Server to move through a complete CloudFormation development cycle without leaving your AI assistant. The documentation search tool retrieved up-to-date resource property references that the AI assistant used to generate a template. The validation tools caught syntax errors and compliance gaps before deployment. When the deployment failed due to missing permissions on the service role (an issue that static analysis cannot detect), you used the troubleshoot tool to correlate stack events with CloudTrail and pinpoint the root cause in seconds.

By combining static validation with runtime diagnostics, you shorten your develop-validate-fix cycle for CloudFormation. Instead of switching between browser tabs, CLI sessions, and the CloudTrail console, you stay in one interface — turning a multi-step troubleshooting session that previously meant switching between consoles, CLI sessions, and CloudTrail into a few prompts in a single conversation.

To get started, explore the companion GitHub repository for the complete sample code. Learn more about the IaC MCP Server in the introductory blog post and the AWS CloudFormation documentation. To set up Kiro, visit kiro.dev.


About the authors

Shuto Yukawa is an Associate Delivery Consultant at AWS Professional Services. He helps customers modernize their applications and adopt cloud-native practices on AWS.

G SS Harsha Vardhan is an Associate Delivery Consultant at AWS Professional Services. He guides customers to migrate and transform their workloads to AWS, driving modernization across people, process, and technology.

Building multi-Region resiliency for AWS CloudFormation custom resource deployment

Post Syndicated from Raman Pujani original https://aws.amazon.com/blogs/architecture/building-multi-region-resiliency-for-aws-cloudformation-custom-resource-deployment/

AWS CloudFormation is the foundational tool of infrastructure-as-code for thousands of organizations running workloads on AWS. But as teams push the boundaries of what CloudFormation can do natively, custom resources have emerged as a powerful extension mechanism that unlocks a broad range of possibilities. Yet, when it comes to building resilient, multi-Region deployments with custom resources, customers quickly discover a gap: there is no built-in multi-Region support. In this post, we will explore that challenge and go over a robust active-active architecture that solves it.

A CloudFormation custom resource allows you to write custom provisioning logic that AWS CloudFormation invokes during stack operations (Create, Update, or Delete). When CloudFormation encounters a custom resource in a template, it sends a lifecycle event to a target, typically an AWS Lambda function through an Amazon Simple Notification Service topic. CloudFormation waits for a response with a presigned URL, and then proceeds or rolls back based on that response.

Customers use Custom Resources for a wide variety of use cases, including:

  • Third-party API integrations to provision resources in external systems (for example, DNS providers, SaaS providers) as part of a CloudFormation stack.
  • Complex initialization logic for seeding databases, generating secrets, or bootstrapping configurations that CloudFormation doesn’t natively support.
  • Cross-account or cross-service orchestration for triggering workflows in other AWS accounts or services during stack lifecycle events.
  • Custom validation and compliance checks enforcing organizational policies before a stack is allowed to complete.
  • Resource types not yet supported natively for bridging the gap until AWS adds first-class support.

In short, Custom Resources turn CloudFormation into a fully extensible orchestration engine instead of only an AWS resource provisioner.

While single-Region deployments can achieve high resilience, multi-Region architectures become essential for organizations that need to meet specific business requirements. These include stringent disaster recovery objectives, data residency mandates, latency-sensitive use cases across geographies, and mission-critical business continuity needs. However, when it comes to CloudFormation Custom Resources, multi-Region design introduces a set of hard problems that CloudFormation does not solve natively:

  • No native fan-out mechanism: CloudFormation stacks in different Regions each trigger their own custom resource events independently. There is no built-in way to coordinate these events across Regions.
  • Duplicate execution risk: If you deploy the same Lambda function handler in multiple Regions to achieve redundancy, both instances may process the same event. This can lead to duplicate side effects (for example, creating the same record twice in a database or calling an external API multiple times).
  • No distributed locking: CloudFormation provides no mechanism to verify that only one handler processes a given event, even when multiple handlers are active.
  • No automated failover: If the primary Region’s Lambda function handler fails, there is no built-in mechanism to automatically route the event to a secondary Region.
  • Idempotency is your problem: Helping verify that retries and failover scenarios don’t cause unintended duplicate operations is entirely the responsibility of the developer.

Until now, these gaps meant that teams either accept the risk of single-Region custom resource handlers (a reliability concern) or build complex, bespoke solutions to handle multi-Region scenarios.

Walkthrough

Prerequisites

Solution approach

This proposed architecture delivers an active-active multi-Region solution for CloudFormation custom resource processing. It is designed around four core principles:

  • Active-Active processing: Both the primary Region (us-east-1) and secondary Region (us-west-2) are always live and capable of handling events.
  • No duplicate execution: A DynamoDB Global Table-based distributed locking mechanism helps verify that only one Region processes any given event, regardless of which Region receives it first.
  • Idempotency mechanism: Every request is tracked by state, so retries and failover scenarios are designed to avoid duplicate side effects.
  • Fully automated failover: Amazon Application Recovery Controller detects failures and triggers failover without manual intervention.

This architecture avoids the single points of failure inherent in single-Region custom resource designs while preventing the duplicate processing risks of naive multi-Region approaches. This architecture is ideal for mission-critical workloads where regional failures cannot be tolerated.

The following section provides a detailed walkthrough of how this architecture processes a CloudFormation lifecycle event from end to end.

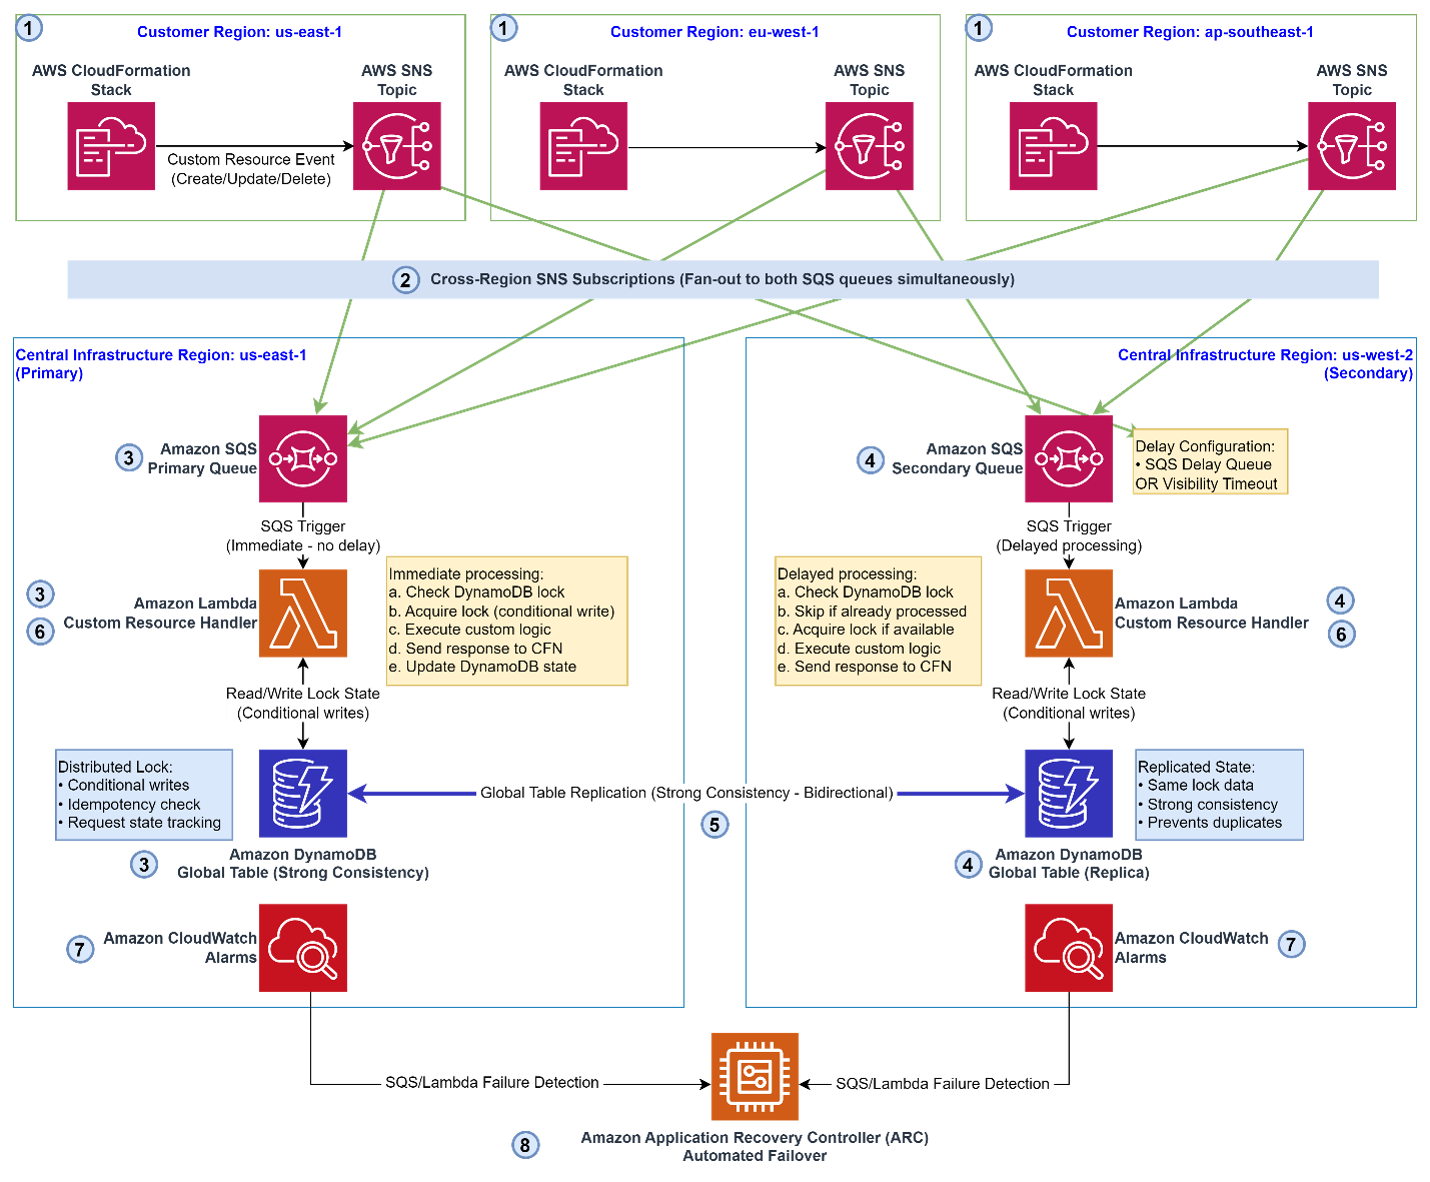
This architecture diagram describes a multi-Region CloudFormation custom resource architecture operating in an Active-Active configuration. It handles CloudFormation lifecycle events (Create/Update/Delete) with high availability and no duplicate processing across multiple AWS Regions. The architecture uses a central primary Region (us-east-1) and a secondary Region (us-west-2) to process custom resource events, with Amazon DynamoDB Global Tables providing distributed locking and idempotency, and Amazon Application Recovery Controller providing automated failover. Customer AWS Regions fan out events simultaneously to both infrastructure Regions, supporting resilience even if the primary Region fails.

Architecture diagram showing the multi-Region CloudFormation custom resource processing flow with SNS fan-out, SQS queues, Lambda handlers, DynamoDB Global Tables for distributed locking, and Amazon Application Recovery Controller for automated failover

Step 1: Event initiation (Customer Regions)

A CloudFormation Stack in one of the customer Regions (us-east-1, eu-west-1, or ap-southeast-1) initiates a Create, Update, or Delete lifecycle event. Along with the event payload, CloudFormation generates a presigned response URL that the handler must call to signal success or failure. This event is published to a local Amazon Simple Notification Service (SNS) topic within that customer Region.

Step 2: Cross-Region fan-out with SNS subscriptions

The Amazon SNS topic is configured with cross-region subscriptions that simultaneously fan out the event to two Amazon SQS queues in the central infrastructure AWS Regions:

  • Primary SQS queue: Central Infrastructure Region: us-east-1.
  • Secondary SQS queue: Central Infrastructure Region: us-west-2.

Both queues receive the event at the same time, setting up the Active-Active processing model.

Step 3: Primary Lambda function handler (Immediate processing)

The Primary SQS queue triggers the Primary Lambda Custom Resource Handler immediately, with no delay. The Lambda function executes the following steps:

  • Check the DynamoDB Global Table for an existing lock on this request.
  • Acquire the lock by using a conditional write (only succeeds if no lock exists, preventing race conditions).
  • Execute the custom resource business logic.
  • Send a SUCCESS or FAILED response back to CloudFormation using the presigned URL.
  • Update the DynamoDB state to mark the request as fully processed.

Step 4: Secondary Lambda function handler (Delayed processing)

The Secondary SQS queue is configured with a delay, implemented by using either an SQS Delay Queue or a Visibility Timeout. After this delay, the Secondary Lambda Custom Resource Handler runs:

  • Check the DynamoDB Global Table Replica for an existing lock.
  • Skip processing if the primary has already handled the request (idempotency check).
  • Acquire the lock if the primary has not yet processed it (failover scenario).
  • Execute the custom resource logic if the lock was successfully acquired.
  • Send the response to CloudFormation.

The delay is intended to give the primary Region time to process the event first. The secondary only takes over if the primary has not completed processing within the delay window.

Step 5: DynamoDB Global Tables: Distributed locking and idempotency

Amazon DynamoDB Global Tables are the backbone of coordination in this architecture. Both Regions read from and write to the Global Table with strong consistency. The table tracks:

  • Lock state: Which Region holds the lock for a given request.
  • Idempotency records: Whether a request has already been processed.
  • Request state: The full lifecycle status of each event.

Bidirectional replication is designed to help maintain both Regions with the latest state, supporting the lock mechanism’s reliability despite network partitions or regional degradation.

Step 6: CloudFormation response

After either the primary or secondary Lambda function handler completes processing, CloudFormation receives the SUCCESS or FAILED callback using the pre-signed URL. Based on this response, CloudFormation either continues the stack operation or initiates a rollback.

Step 7: Amazon CloudWatch monitoring

Amazon CloudWatch alarms continuously monitor SQS queue depth and Lambda execution health in both Regions. These alarms serve as the early warning system for the automated failover mechanism.

Step 8: Automated failover with ARC

If the primary Region (us-east-1) experiences a failure, CloudWatch detects it and triggers Amazon Application Recovery Controller to initiate automated failover to the secondary Region (us-west-2). No manual intervention is typically required. The secondary Region is designed to take over processing responsibilities.

Clean up

Delete resources created using the following AWS services in every Region to avoid additional costs:

  • ARC.
  • SNS topic.
  • SQS queue/messages.
  • DynamoDB table.
  • Lambda code.
  • CloudWatch Log Groups.
  • IAM roles.
  • CloudFormation (if used for automation).
  • Any other AWS service used for customizing your deployment.

Conclusion

CloudFormation Custom Resources are an indispensable tool for teams building sophisticated infrastructure automation on AWS. However, the lack of native multi-Region support has long been a barrier to building truly resilient custom resource architectures.

This architecture addresses the major challenge directly:

  • Resilience: Active-Active design means no single Region is a bottleneck or single point of failure.
  • Correctness: Amazon DynamoDB distributed locking and idempotency designed to eliminate duplicate processing.
  • Automation: Amazon Application Recovery Controller-driven failover removes the need for manual intervention during regional outages.
  • Scalability: The fan-out model with SNS cross-Region subscriptions supports multiple customer Regions simultaneously.

For teams operating at scale across multiple AWS Regions, this architecture provides a blueprint for extending the power of CloudFormation without sacrificing reliability. Whether you’re managing compliance-driven multi-Region deployments or building for global high availability, this pattern gives you a foundation for resilient custom resource processing.

Call to action

Refer to the following content to learn more about relevant AWS services:

AWS Weekly Roundup: Claude Sonnet 5 on AWS, Amazon WorkSpaces for AI agents, AWS service availability updates, and more (July 6, 2026)

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-sonnet-5-on-aws-amazon-workspaces-for-ai-agents-aws-service-availability-updates-and-more-july-6-2026/

A couple of editions ago I wrote about what I find so energizing about working with startups. Last week I got a fresh dose of it: I spent a few days with the AWS Startups team, listening to stories of founders talking about the problems they’re actually solving. One story that stayed with me came from Marco Negreiros, founder of EyeCare Health, a Brazilian healthtech expanding access to eye care. He shared a striking fact: more than 70% of Brazilian municipalities don’t have a single ophthalmologist. His answer was to put a vision test on the one device almost everyone already carries, the smartphone, so a basic eye screening no longer depends on living near a clinic. Watching a founder turn a gap that big into something that concrete is exactly why I love this space.

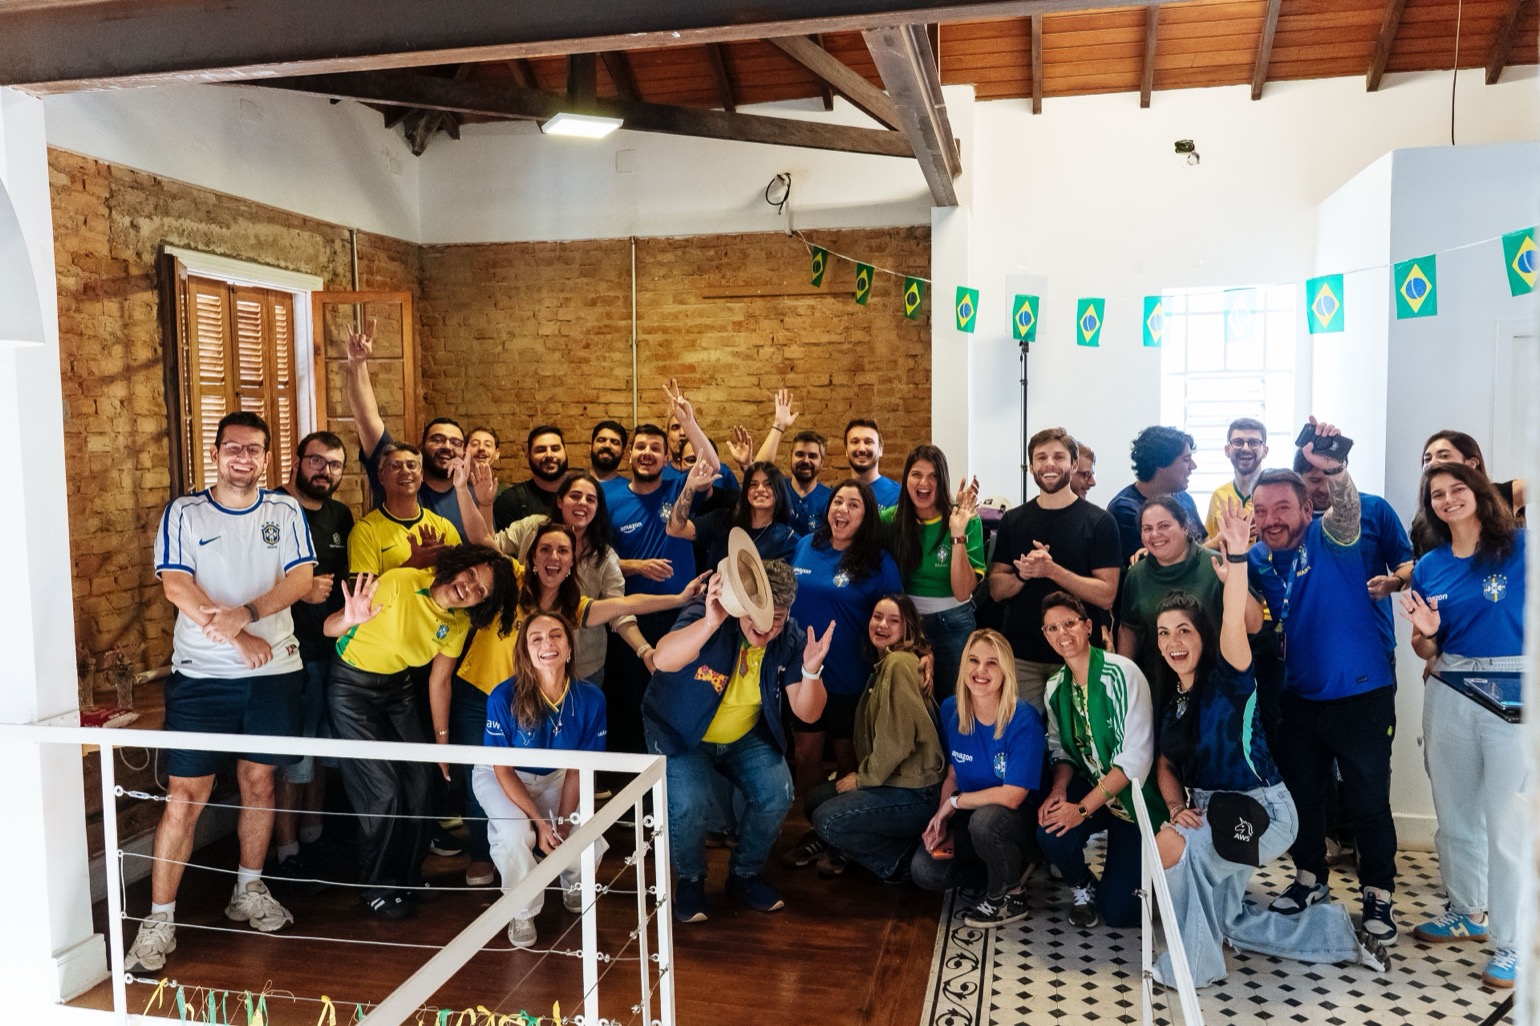
AWS Startups team get-together with founders in Brazil

This week, I’ll take a closer look at some key launches, and then cover the quarterly AWS Service Availability updates.

Last week’s launches
Here are some of the launches covered from this past week in the AWS News Blog:

Here are some launches and updates that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

AWS Service Availability Updates
When the availability of an AWS service or feature changes, we provide customers guidance in AWS Product Lifecycle Changes on available alternatives and support for migration so that disruptions to your operations are minimized. The following lifecycle changes were updated on June 30, 2026.

Services moving to Maintenance (no longer accessible to new customers starting July 30, 2026):

Services entering Sunset:

Services reaching End of Support (as of June 30, 2026):

  • Amazon Chime SDK – Carrier Voice Focus
  • Amazon SageMaker AI – Ground Truth Plus

We understand that changes in availability can impact your operations. For specific guidance, consult the relevant service documentation or contact AWS Support.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits – AWS Summits are free events that bring the cloud and AI community together to connect, learn, and explore the latest technologies. Browse the full calendar to find a Summit near you in the second half of 2026.
  • AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders. If you’re in Latin America, don’t miss AWS Community Day Belo Horizonte on August 22. Registration is open at awscommunityday.com.br.

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Daniel Abib

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

How CloudFormation Express mode accelerates your development cycle

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/how-cloudformation-express-mode-accelerates-your-development-cycle/

AWS CloudFormation helps you model and provision cloud infrastructure as code using JSON or YAML templates, or through tools like the AWS Cloud Development Kit (CDK). Whether you create stacks directly, use change sets for preview, or deploy through CI/CD pipelines and AI agents, the speed of your deployment cycle directly impacts how fast you can iterate.

In March 2024, we published How we sped up AWS CloudFormation deployments with optimistic stabilization, where we explained how CloudFormation provisions resources and what happens during stabilization. That post introduced the CONFIGURATION_COMPLETE event and the optimistic stabilization strategy that reduced deployment times by up to 40%. Today, CloudFormation express mode takes this further.

Express mode is recommended for development workflows where you iterate frequently. It makes your deployments complete faster so you can get immediate feedback. For production deployments where you need resources ready to serve traffic before proceeding, the default behavior remains the right choice. Combined with pre-deployment validation, which catches template errors before provisioning begins, Express mode completes the iterate-faster picture: validate in seconds, deploy in seconds. To understand what express mode gives you, you first need to understand what CloudFormation has always done during deployment.

What CloudFormation does during deployment

When you add an AWS::SQS::Queue to your template and deploy, the queue is created. But can it receive messages yet? Often, no. There’s a window between “resource created” and “resource can serve traffic.” This is true across AWS services. An EC2 instance is “launched” before it can respond to HTTP requests. A CloudFront distribution is “created” before it propagates to edge locations worldwide. An ECS service is “active” before its containers pass health checks and reach desired capacity. And a Lambda function deletion isn’t complete until its network interfaces are cleaned up.

Figure 1 - Single resource lifecycle phases

Figure 1: Single resource lifecycle phases

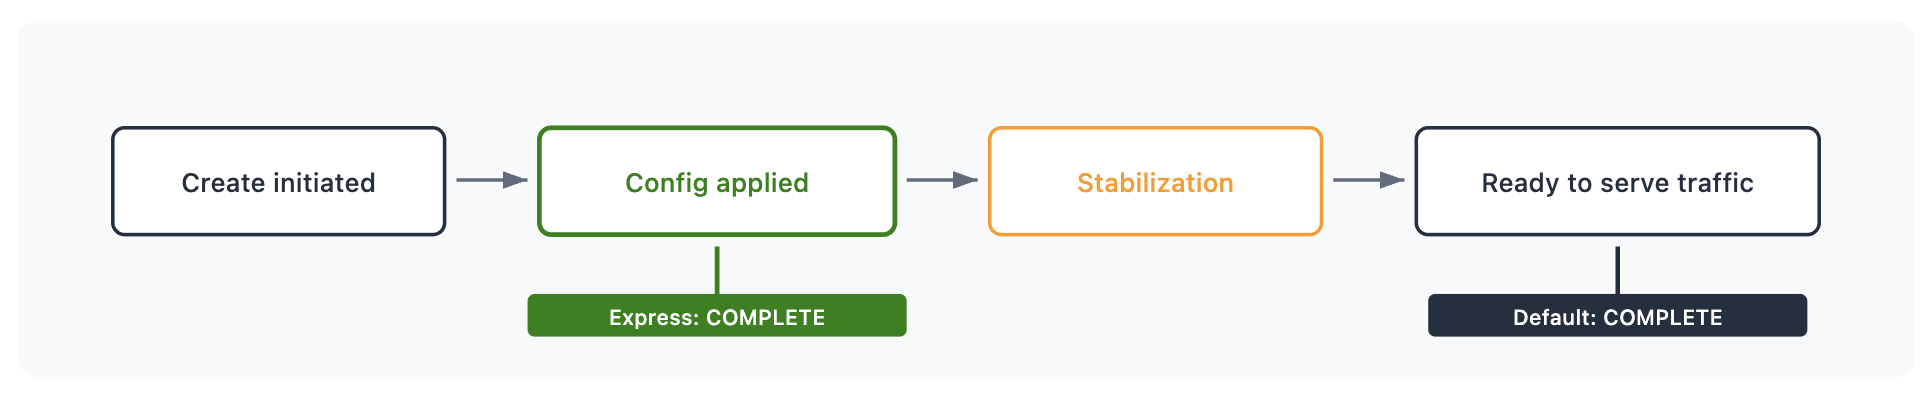
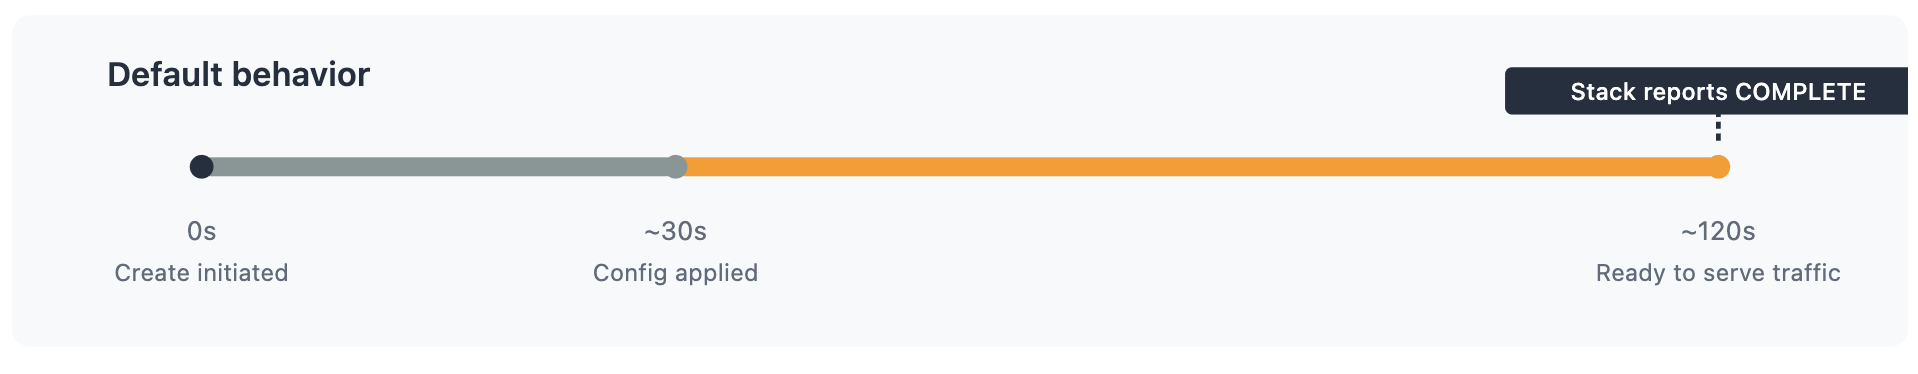
This process is called stabilization. Stabilization means that when a stack operation reports CREATE_COMPLETE, the resources can serve traffic. This is useful for production pipelines where “stack complete” should mean “ready to shift traffic.” Now, with express mode, you have a second option.

Figure 2 - Default deployment mode behavior timeline

Figure 2: Default deployment mode behavior timeline

What Express mode changes

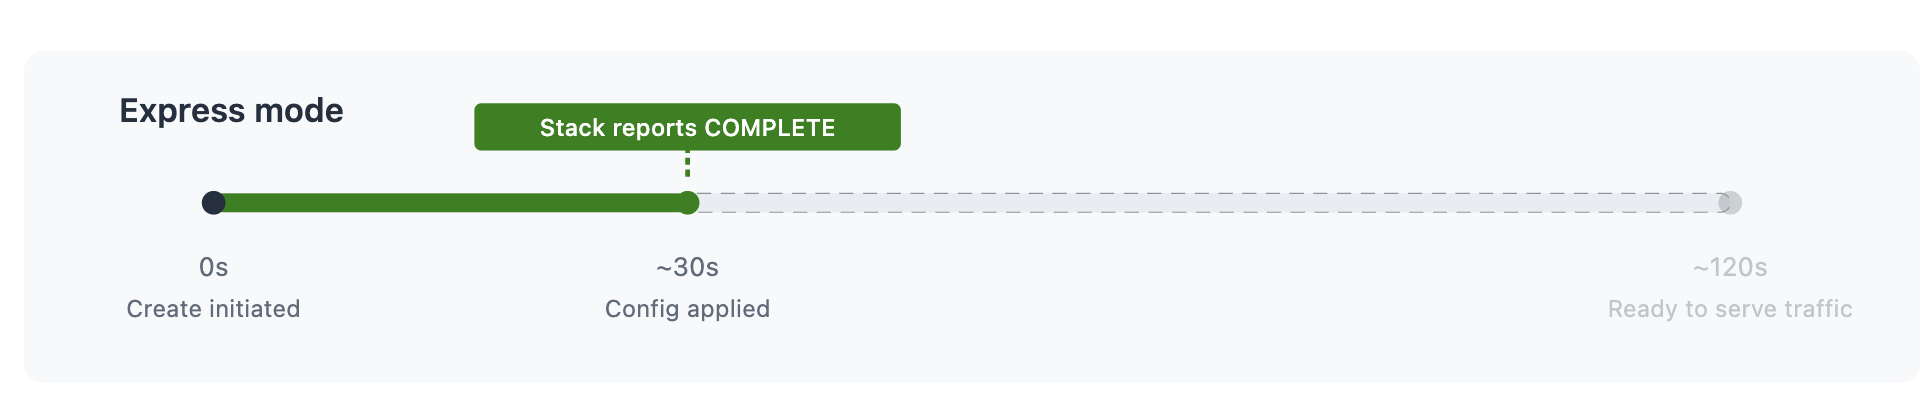
Express mode gives you control over when you want CloudFormation to report completion. With express mode, CloudFormation completes the stack operation as soon as resource configuration is applied. Resources continue becoming ready to serve traffic in the background. Regardless of mode, CloudFormation still:

  • Respects resource dependencies within the stack – if a resource references another resource’s ID or attribute, the referenced resource’s configuration is confirmed first. Resources with no dependencies on each other proceed in parallel.
  • Creates, updates, or deletes each resource the same way
  • Retries dependent resources that encounter transient failures during the operation

Here’s what that looks like for a deployment:Figure 3 - Express mode timeline

Figure 3: Express mode timeline

The resource takes the same time to become ready to serve traffic in both cases. Express mode makes your iteration cycle faster by not blocking you on the stabilization wait.

When this matters

Development iteration

You’re building a VPC with subnets, a security group, and an ALB. You need the ALB’s DNS name and the security group ID to configure the next layer of your application. You don’t need to send traffic to the ALB right now. You just need to know it exists and get its attributes. With Express mode, you get the ARN, the DNS name, and the security group bindings in seconds. You proceed to your next iteration.

AI agent workflows

An AI agent iterating on infrastructure needs a tight feedback loop: deploy, observe the result, adjust, deploy again. The agent doesn’t need the CloudFront distribution to propagate globally before deciding whether the template is correct. It needs confirmation that the configuration was accepted.

Express mode turns a 5-10 minute CloudFront deployment into a sub-minute confirmation. The agent can validate, refine, and redeploy multiple times in the window a single default deployment would have taken.

Dependent stack deployments

When you deploy multiple stacks in sequence, each stack operation completes faster with Express mode. Whether dependencies exist within a stack or across stacks via import/export, Express mode handles retries and waits to make sure dependent resources can still be provisioned. It moves faster without breaking your dependency chain

Getting started

Enable Express mode per operation with a single parameter:

aws cloudformation create-stack \   
     --stack-name my-app \   
    --template-body file://template.yaml \   
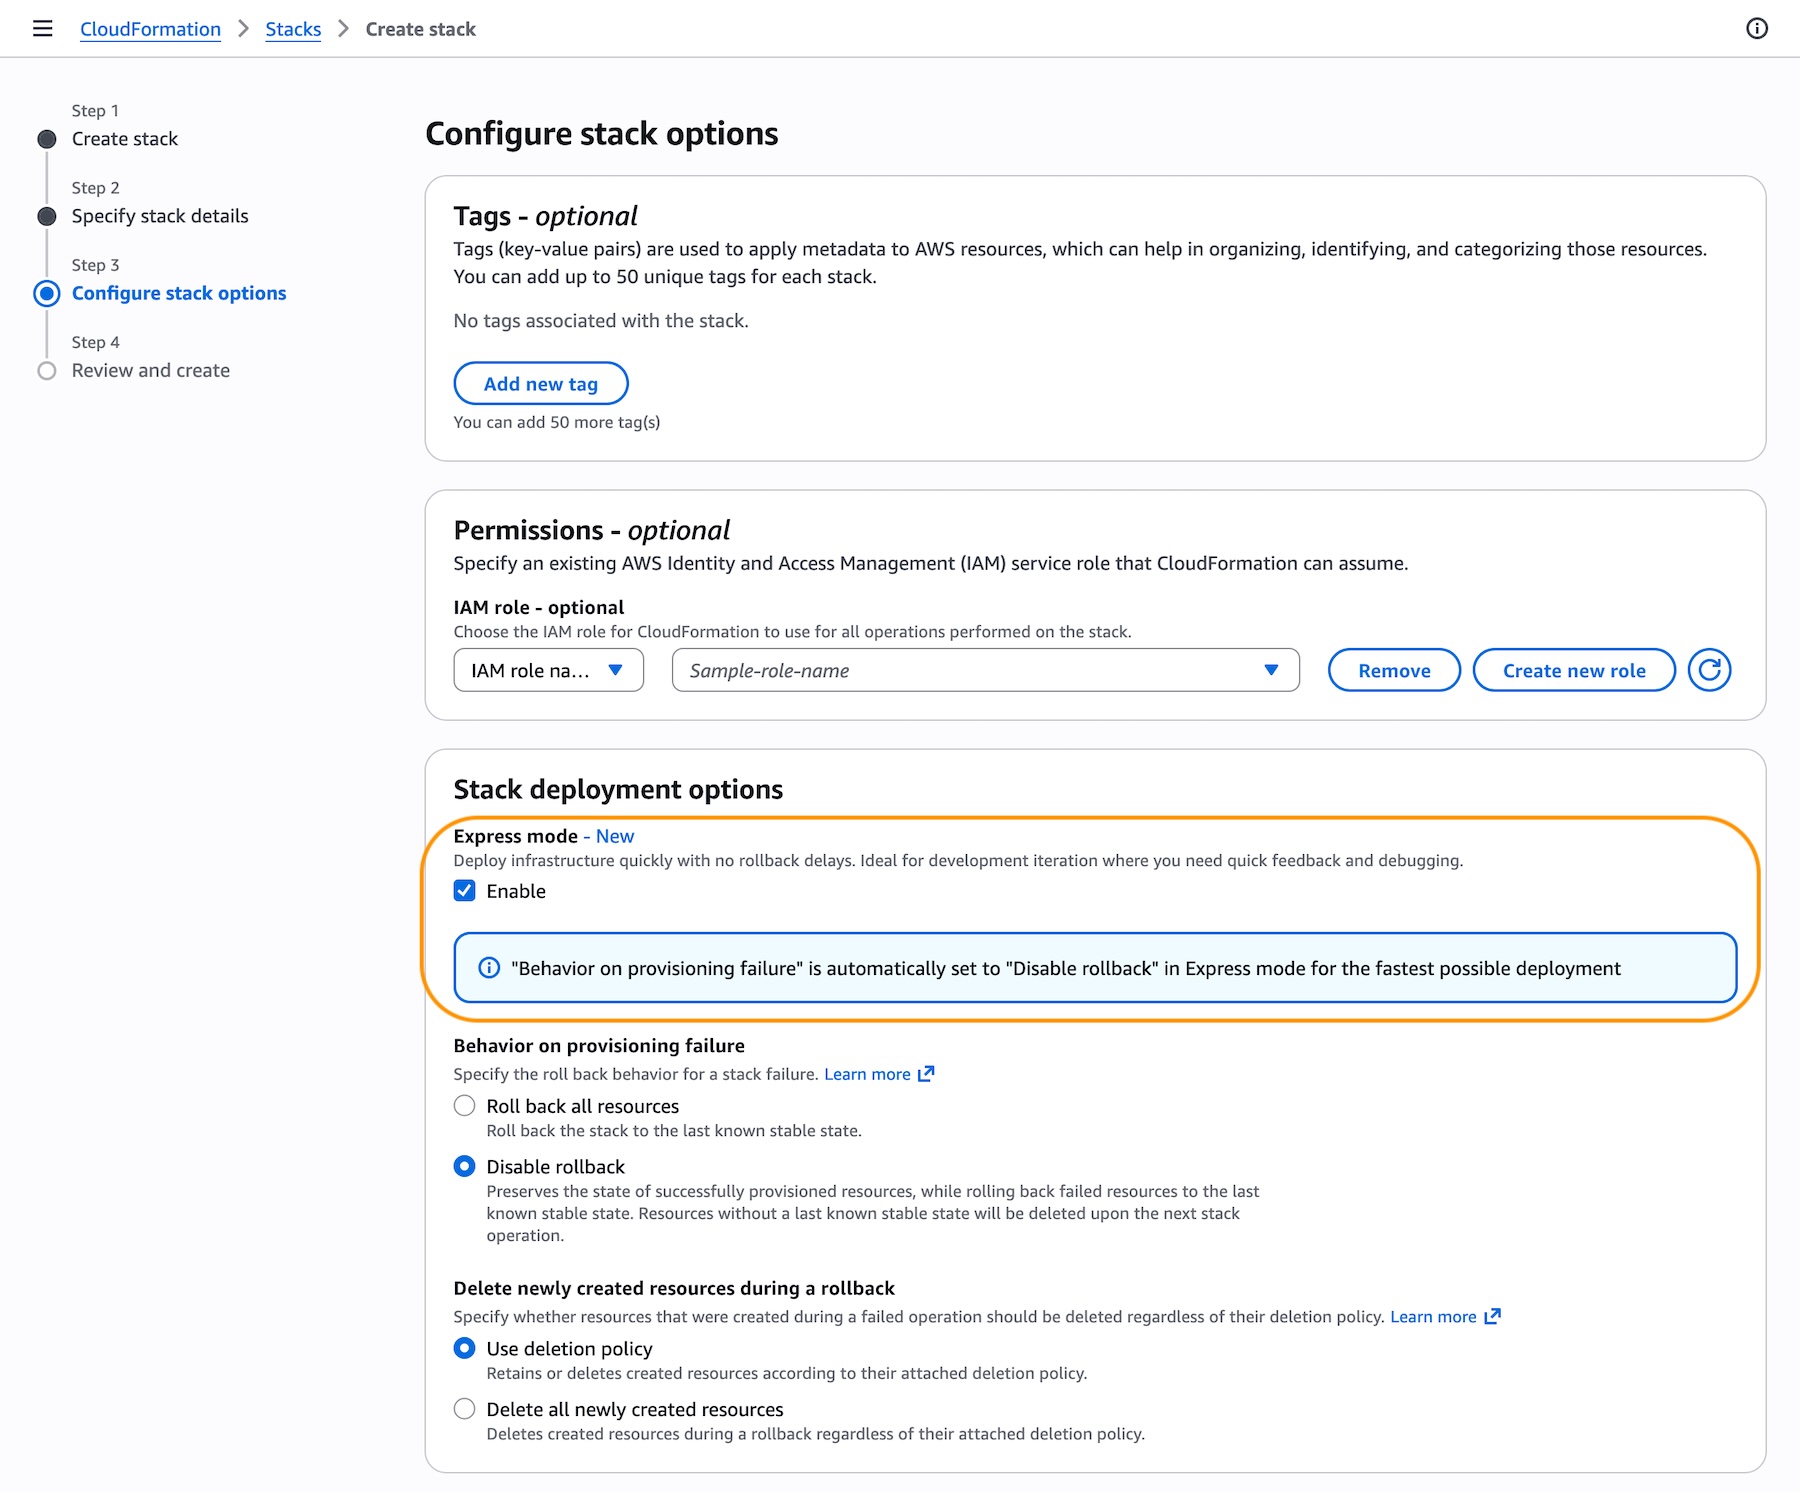
    --deployment-config '{"mode": "EXPRESS"}'

Express mode disables rollback by default for faster iteration. If a resource fails to configure, the stack stays in place and you can fix and retry immediately. To re-enable rollback:

--deployment-config '{"mode": "EXPRESS", "disableRollback": false}'

With CDK

cdk deploy --express  

#enable rollback  
cdk deploy --express --rollback

With SAM

Use the --express flag with sam deploy or sam sync:

sam deploy --express 

sam sync --express

To persist the setting, add --save-params and Express mode is saved to your samconfig.toml:

sam deploy --express --save-params

The --disable-rollback flag works alongside --express to control rollback behavior within the deployment configuration.

No template changes. No new resource types. The same template deploys the same resources. You’re choosing when to receive the “done” signal.

Additional considerations

Change sets: Express mode is supported with change sets. Specify --deployment-config at create-change-set time, and the configuration is stored with the change set and applied when executed.

Nested stacks: When you enable Express mode on a parent stack, it propagates to all nested stacks in the hierarchy. All resources across the hierarchy complete when configuration is applied.

For a complete list of supported features and limitations, see the CloudFormation Express mode documentation.

Conclusion

Express mode gives you immediate confirmation that your infrastructure configuration is applied, so you can move to your next iteration without waiting for stabilization. It separates “is my configuration correct” from “are my resources serving traffic” and lets you decide which question you need answered right now.

For development iteration, AI agent workflows, and dependent stack deployments where you need resource identifiers rather than traffic readiness, Express mode delivers that answer much more quickly. For production deployments where “stack complete” should mean “ready to serve traffic,” the default behavior remains the right choice.

Related resources

Idriss Laouali Abdou

Idriss is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Ship infrastructure faster with CloudFormation and CDK pre-deployment validation on every stack operation

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/ship-infrastructure-faster-with-cloudformation-and-cdk-pre-deployment-validation-on-every-stack-operation/

AWS CloudFormation helps you model and provision cloud infrastructure as code using JSON or YAML templates, or through tools like the AWS Cloud Development Kit (CDK). Whether you create stacks directly, use change sets for preview, or deploy through CI/CD pipelines and AI agents, fast feedback on template errors is critical to development velocity.

Previously, CloudFormation introduced pre-deployment validation during change set creation, catching property syntax errors, resource name conflicts, and S3 bucket emptiness constraints before execution.

Today, we are announcing that pre-deployment validation now runs automatically on every CreateStack and UpdateStack operation, so every deployment path benefits from pre-deployment checks with no configuration required. We are also introducing three new validation checks (Service Quotas limit exceeded, AWS Config Recorder conflicts, and ECR repository delete readiness), a new DisableValidation parameter for operation-level control, and the cdk validate command that leverages CloudFormation pre-deployment validation as part of the CDK developer experience.

In this blog post, we will walk you through how these capabilities work in practice. You will learn how to:

  • Catch property syntax errors and resource name conflicts on CreateStack and UpdateStack before any resources are provisioned
  • Review new WARN-mode validations (service quotas, Config Recorder, ECR delete readiness) during change set creation
  • Use cdk validate to get a validation report with construct-level source tracing
  • Control validation behavior with the DisableValidation parameter when you need to skip checks

Key Capabilities

  • Pre-deployment validation on all stack operations: Property syntax validation and resource name conflict detection (Resource Already Exists) now run in hard-fail mode on CreateStack and UpdateStack, in addition to CreateChangeSet. Errors are caught before any resources are provisioned.
  • Three new validation types: Service Quota validation, AWS Config Recorder conflict detection, and ECR Repository delete readiness checks are now available as warnings during change set creation.
  • CDK validate command: The cdk validate command leverages CloudFormation pre-deployment validation and provides a report with construct-level source tracing that maps errors back to your CDK code.
  • DisableValidation parameter: Operation-level control to skip pre-deployment validation when you need to prioritize deployment speed or bypass a known issue.

How It Works

Understanding Validation Modes

CloudFormation pre-deployment validation operates in two modes that determine how validation failures are handled:

  • FAIL mode stops the stack operation when validation detects errors, ensuring problematic templates cannot proceed to deployment. This applies to property syntax errors and resource name conflicts on CreateStack, UpdateStack, and CreateChangeSet operations.
  • WARN mode allows the operation to proceed despite validation findings, providing warnings that you can review and address before execution. This applies to service quota limits, AWS Config Recorder conflicts, and ECR repository delete readiness checks on CreateChangeSet.

What happens when validation fails:

  • CreateStack: Operation stops before any resources are provisioned.
  • UpdateStack: Operation stops, stack remains in its current state with no resources modified.
  • CreateChangeSet: Change set is not executable. Change set status shows FAILED.

The following scenarios demonstrate how pre-deployment validation works across different stack operations.

Scenario 1: Property Validation on CreateStack

CloudFormation evaluates each resource property definition before provisioning begins. The following template contains several common resource property errors:

Template (dashboard-stack.yaml)

AWSTemplateFormatVersion: "2010-09-09"
Description: Dashboard stack with property validation errors

Resources:
  Dashboard04:
    Type: "AWS::CloudWatch::Dashboard"
    Properties:
      DashboardName: "MyDashboard"

  LogStream08:
    Type: "AWS::Logs::LogStream"
    Properties:
      LogGroupName: "/aws/my-app"
      LogStreamName:                        # Expected string, found JSONArray
        - "stream-1"
        - "stream-2"

  MetricFilter03:
    Type: "AWS::Logs::MetricFilter"
    Properties:
      LogGroupName: "/aws/my-app"
      SomeUnsupportedProperty: "value"      # Unsupported property
      MetricTransformations:
        - MetricName: "ErrorCount"
          MetricNamespace: "MyApp"
          MetricValue: "1"

Step 1: Create Stack

aws cloudformation create-stack \
    --stack-name "dashboard-stack" \
    --template-body file://dashboard-stack.yaml

The command returns the stack ARN and operation begins. Pre-deployment validation runs automatically before any resources are provisioned.

Step 2: Check Validation Results

Use the describe-events API to review validation results:

aws cloudformation describe-events \
    --stack-name "dashboard-stack"

Example output:

The stack creation stopped before any resources were provisioned. Each validation error includes the logical resource ID, resource type, and a precise status reason describing the property issue.

{
    "OperationEvents": [
        {
            "EventId": "ed0f6cc4-3f85-4ad9-abc3-1f9aad2ab931",
            "StackId": "arn:aws:cloudformation:us-west-1:1234:stack/dashboard-stack/6877f3c0-73e6-11f1-a1e1-02ff57e5af93",
            "OperationId": "68790530-73e6-11f1-a1e1-02ff57e5af93",
            "OperationType": "CREATE_STACK",
            "EventType": "VALIDATION_ERROR",
            "LogicalResourceId": "MetricFilter03",
            "PhysicalResourceId": "",
            "ResourceType": "AWS::Logs::MetricFilter",
            "Timestamp": "2026-06-29T18:14:49.255000+00:00",
            "ValidationFailureMode": "FAIL",
            "ValidationName": "PROPERTY_VALIDATION",
            "ValidationStatus": "FAILED",
            "ValidationStatusReason": "Unsupported property [SomeUnsupportedProperty]",
            "ValidationPath": "/Resources/MetricFilter03/Properties/SomeUnsupportedProperty"
        },
        {
            "EventId": "4f9f12ce-498c-4d79-af31-730238b85139",
            "StackId": "arn:aws:cloudformation:us-west-1:1234:stack/dashboard-stack/6877f3c0-73e6-11f1-a1e1-02ff57e5af93",
            "OperationId": "68790530-73e6-11f1-a1e1-02ff57e5af93",
            "OperationType": "CREATE_STACK",
            "EventType": "VALIDATION_ERROR",
            "LogicalResourceId": "LogStream08",
            "PhysicalResourceId": "",
            "ResourceType": "AWS::Logs::LogStream",
            "Timestamp": "2026-06-29T18:14:49.255000+00:00",
            "ValidationFailureMode": "FAIL",
            "ValidationName": "PROPERTY_VALIDATION",
            "ValidationStatus": "FAILED",
            "ValidationStatusReason": "Property [LogStreamName] expected type: String, found: JSONArray",
            "ValidationPath": "/Resources/LogStream08/Properties/LogStreamName"
        },
    ]
}

Console Experience

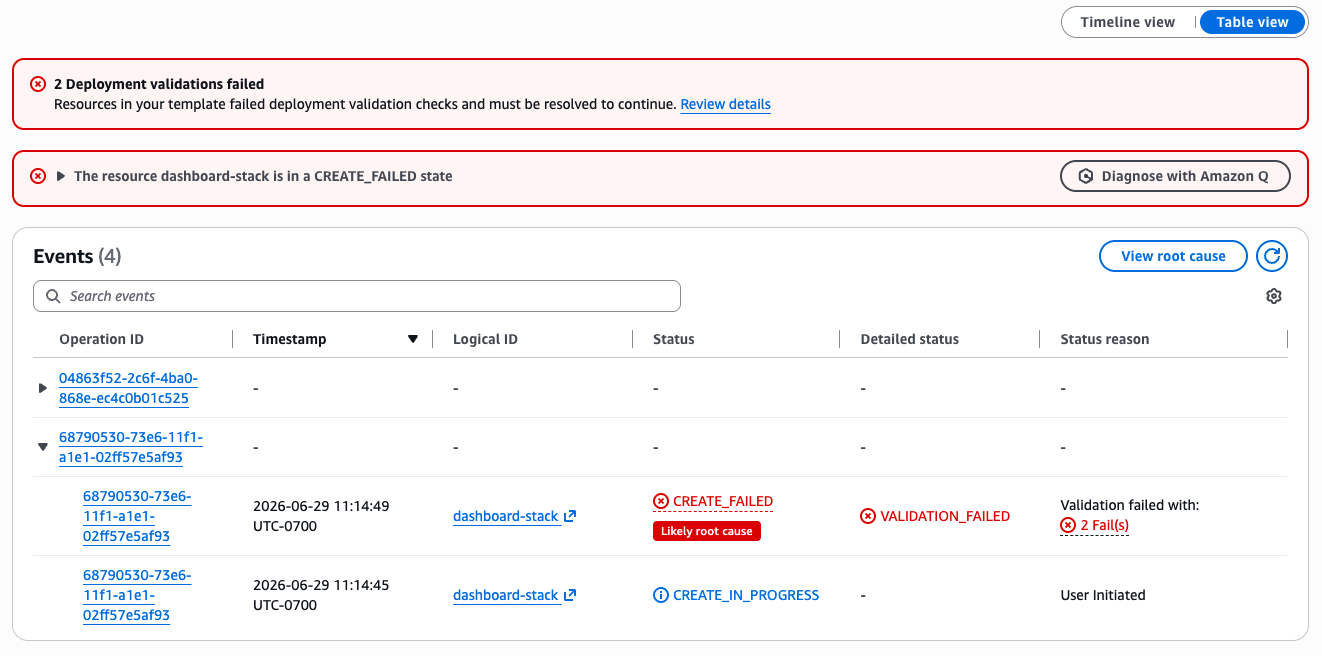
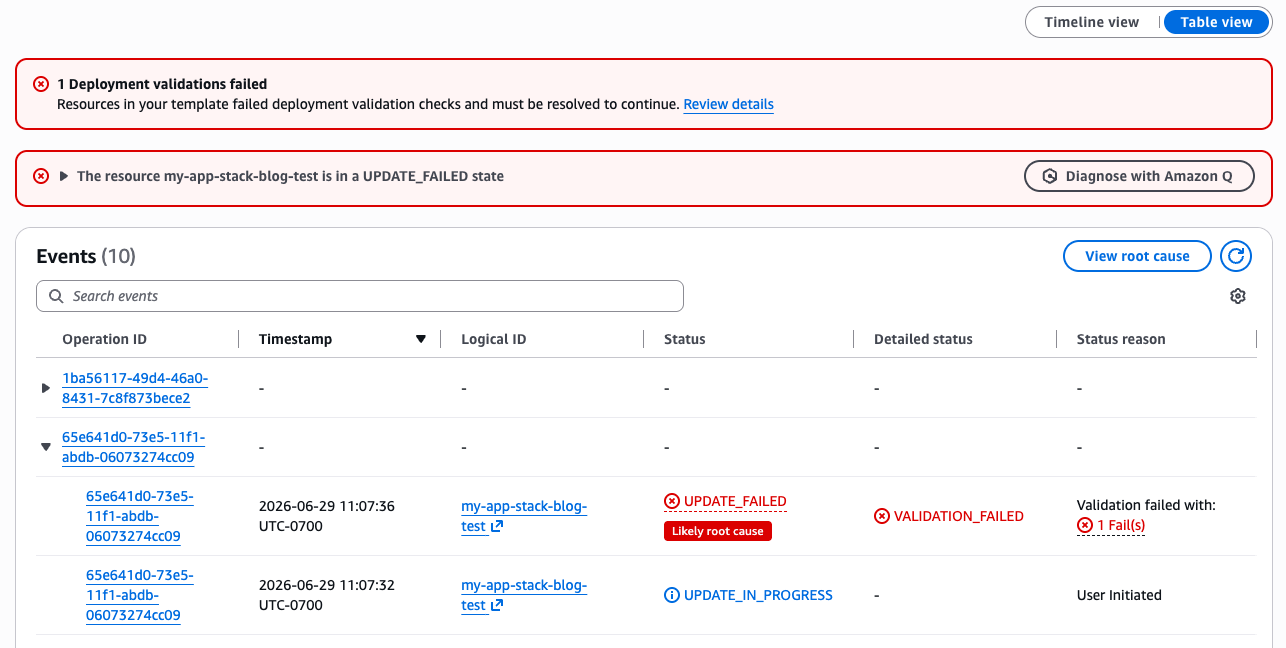
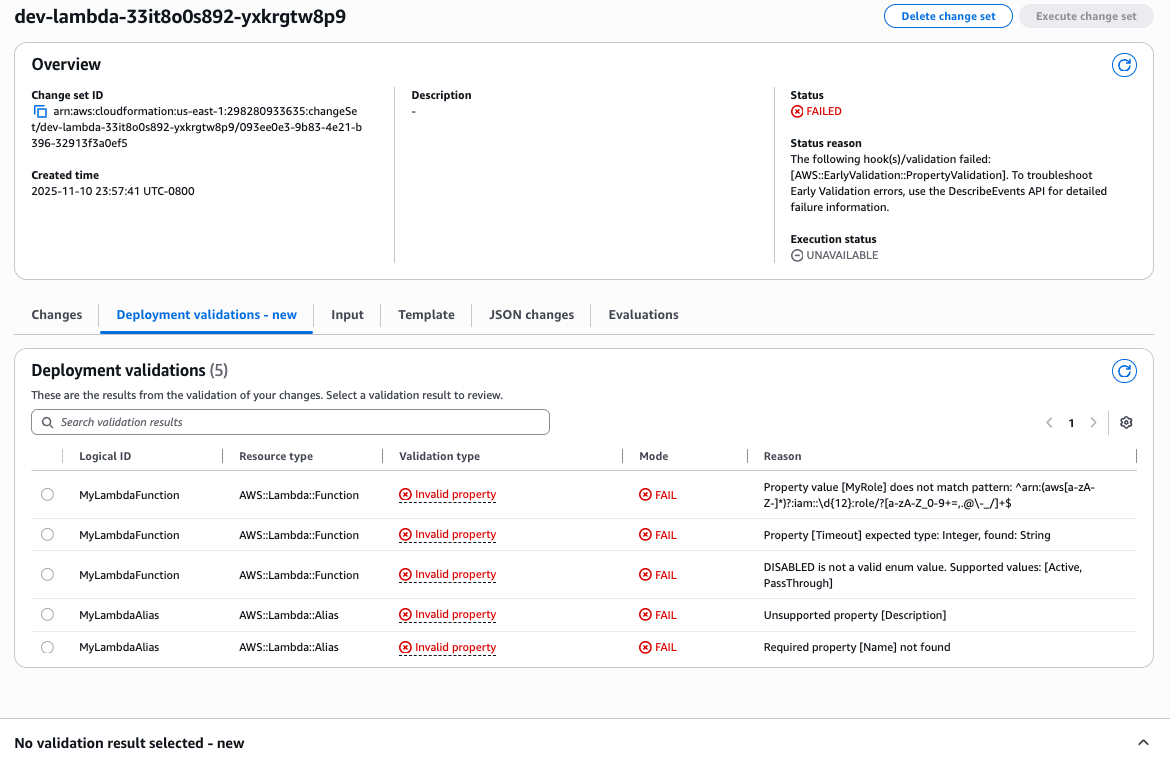
In the CloudFormation console, navigate to your stack’s Events tab and click the operation ID (or the link in the banner or status reason column) to open the Operation view page. The page will open directly on the Deployment validations tab to see the validation results table:

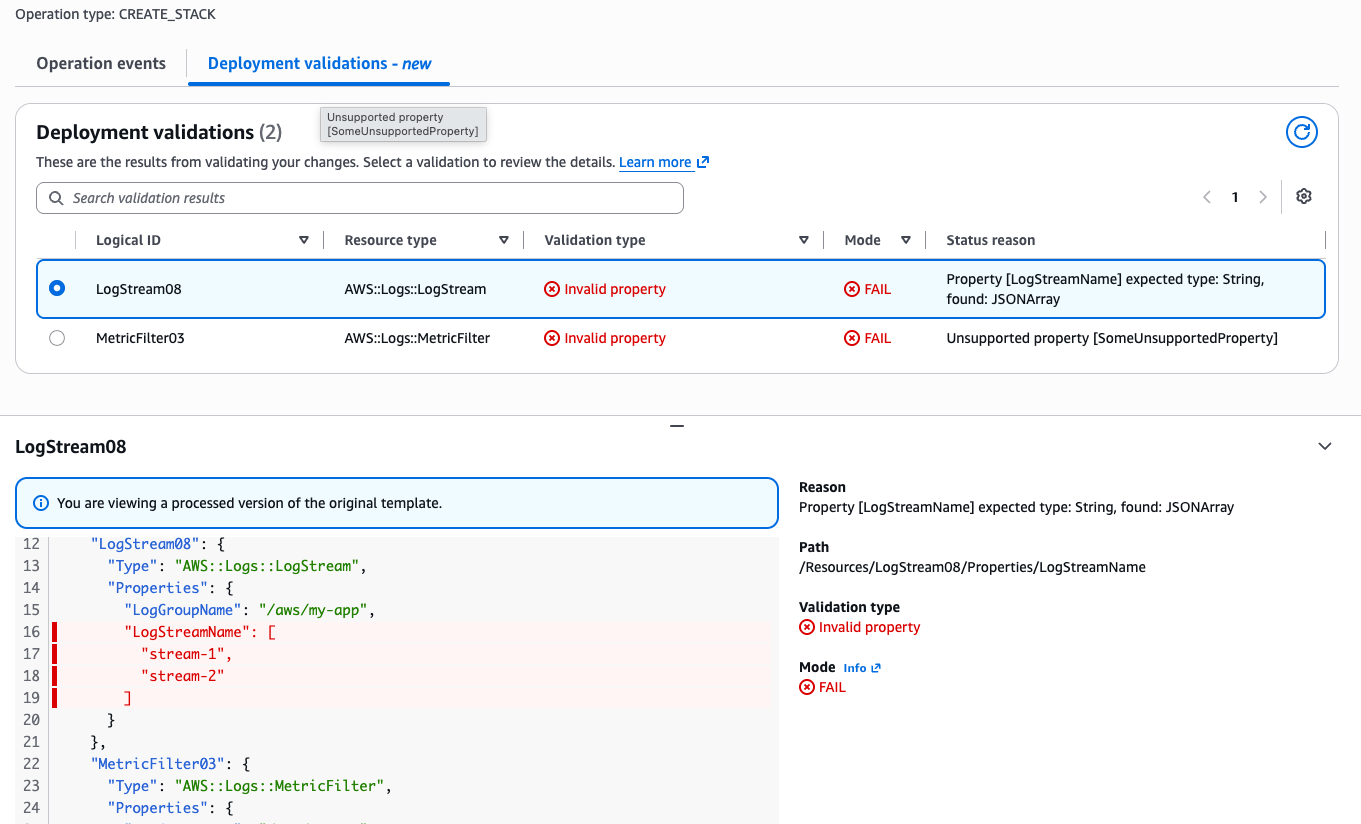
  • LogStream08 (AWS::Logs::LogStream) – FAIL: Property [LogStreamName] expected string, found: JSONArray
  • MetricFilter03 (AWS::Logs::MetricFilter) – FAIL: Unsupported property [SomeUnsupportedProperty]
Figure 1 - Deployment validations tab showing property validation failures on CreateStack

Figure 1: Deployment validations tab showing property validation failures on CreateStack

Figure 2 Deployment validations tab showing property validation failures on CreateStack

Figure 2: Deployment validations tab showing property validation failures on CreateStack

Scenario 2: Resource Name Conflict on UpdateStack

Resource name conflict detection (RAE) identifies when your template specifies a resource name that already exists in your account. This validation now runs on CreateStack and UpdateStack operations in addition to CreateChangeSet.

Template (update-bucket.yaml)

AWSTemplateFormatVersion: "2010-09-09"
Description: Update stack adding a bucket with a conflicting name

Resources:
  ExistingFunction:
    Type: "AWS::Lambda::Function"
    Properties:
      FunctionName: "my-existing-function"
      Runtime: "python3.12"
      Handler: "index.handler"
      Role: !Sub "arn:aws:iam::${AWS::AccountId}:role/lambda-role"
      Code:
        ZipFile: |
          def handler(event, context):
              return {"statusCode": 200}

  ConflictingBucket:
    Type: "AWS::S3::Bucket"
    Properties:
      BucketName: "production-data-bucket"   # Already exists in the account

Update Stack

aws cloudformation update-stack \     
     --stack-name "my-app-stack" \     
     --template-body file://update-bucket.yaml

Validation output (via describe-events):

{
    "OperationEvents": [
        ...
        {
            "EventId": "bde0f986-3b47-48d8-91bc-f384195f842a",
            "StackId": "arn:aws:cloudformation:us-west-1:1234:stack/my-app-stack-blog-test/164ff580-73e5-11f1-ab70-026546ec19e3",
            "OperationId": "65e641d0-73e5-11f1-abdb-06073274cc09",
            "OperationType": "UPDATE_STACK",
            "EventType": "VALIDATION_ERROR",
            "LogicalResourceId": "ConflictingBucket",
            "PhysicalResourceId": "",
            "ResourceType": "AWS::S3::Bucket",
            "Timestamp": "2026-06-29T18:07:36.139000+00:00",
            "ValidationFailureMode": "FAIL",
            "ValidationName": "NAME_CONFLICT_VALIDATION",
            "ValidationStatus": "FAILED",
            "ValidationStatusReason": "Resource of type 'AWS::S3::Bucket' with identifier 'production-data-bucket-blog-test-208004920468' already exists.",
            "ValidationPath": "/Resources/ConflictingBucket"
        },
        ...
    ]
}

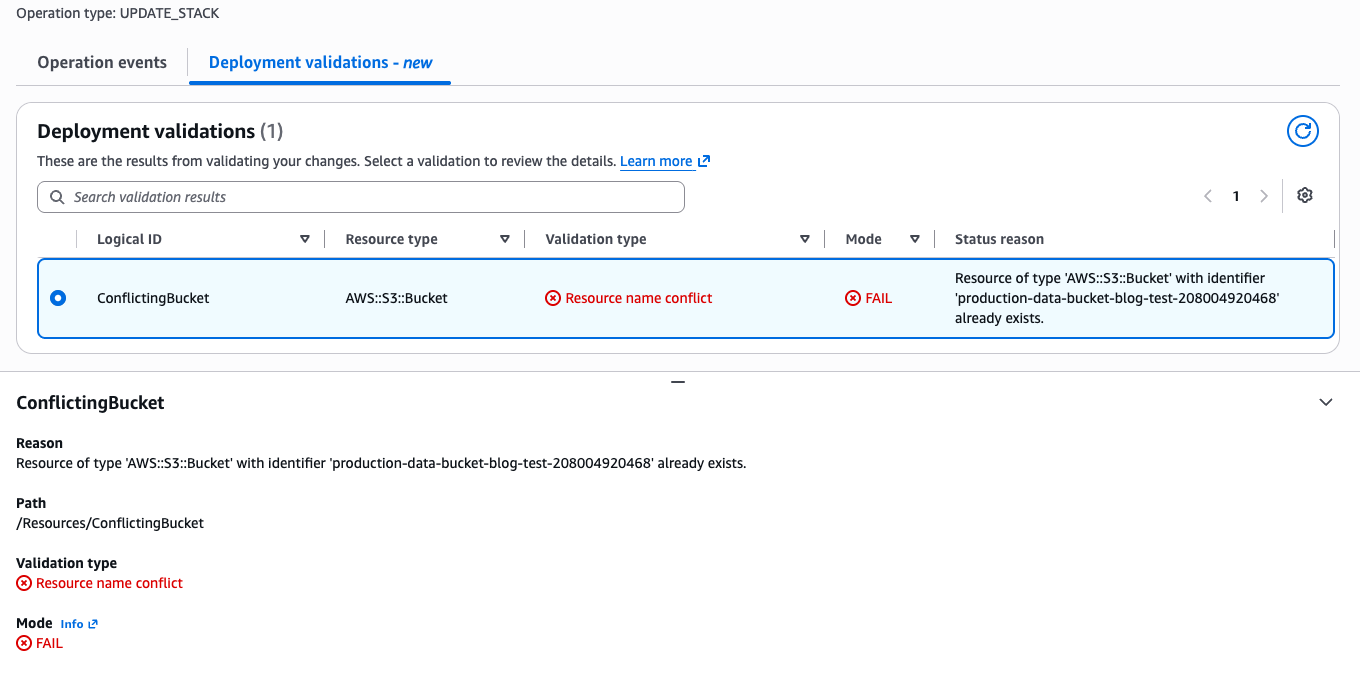
The update stops before any resources are modified. You can either rename the resource in your template or remove the existing resource that causes the conflict.

Figure 3 - Resource Name Conflict on UpdateStack Event tab

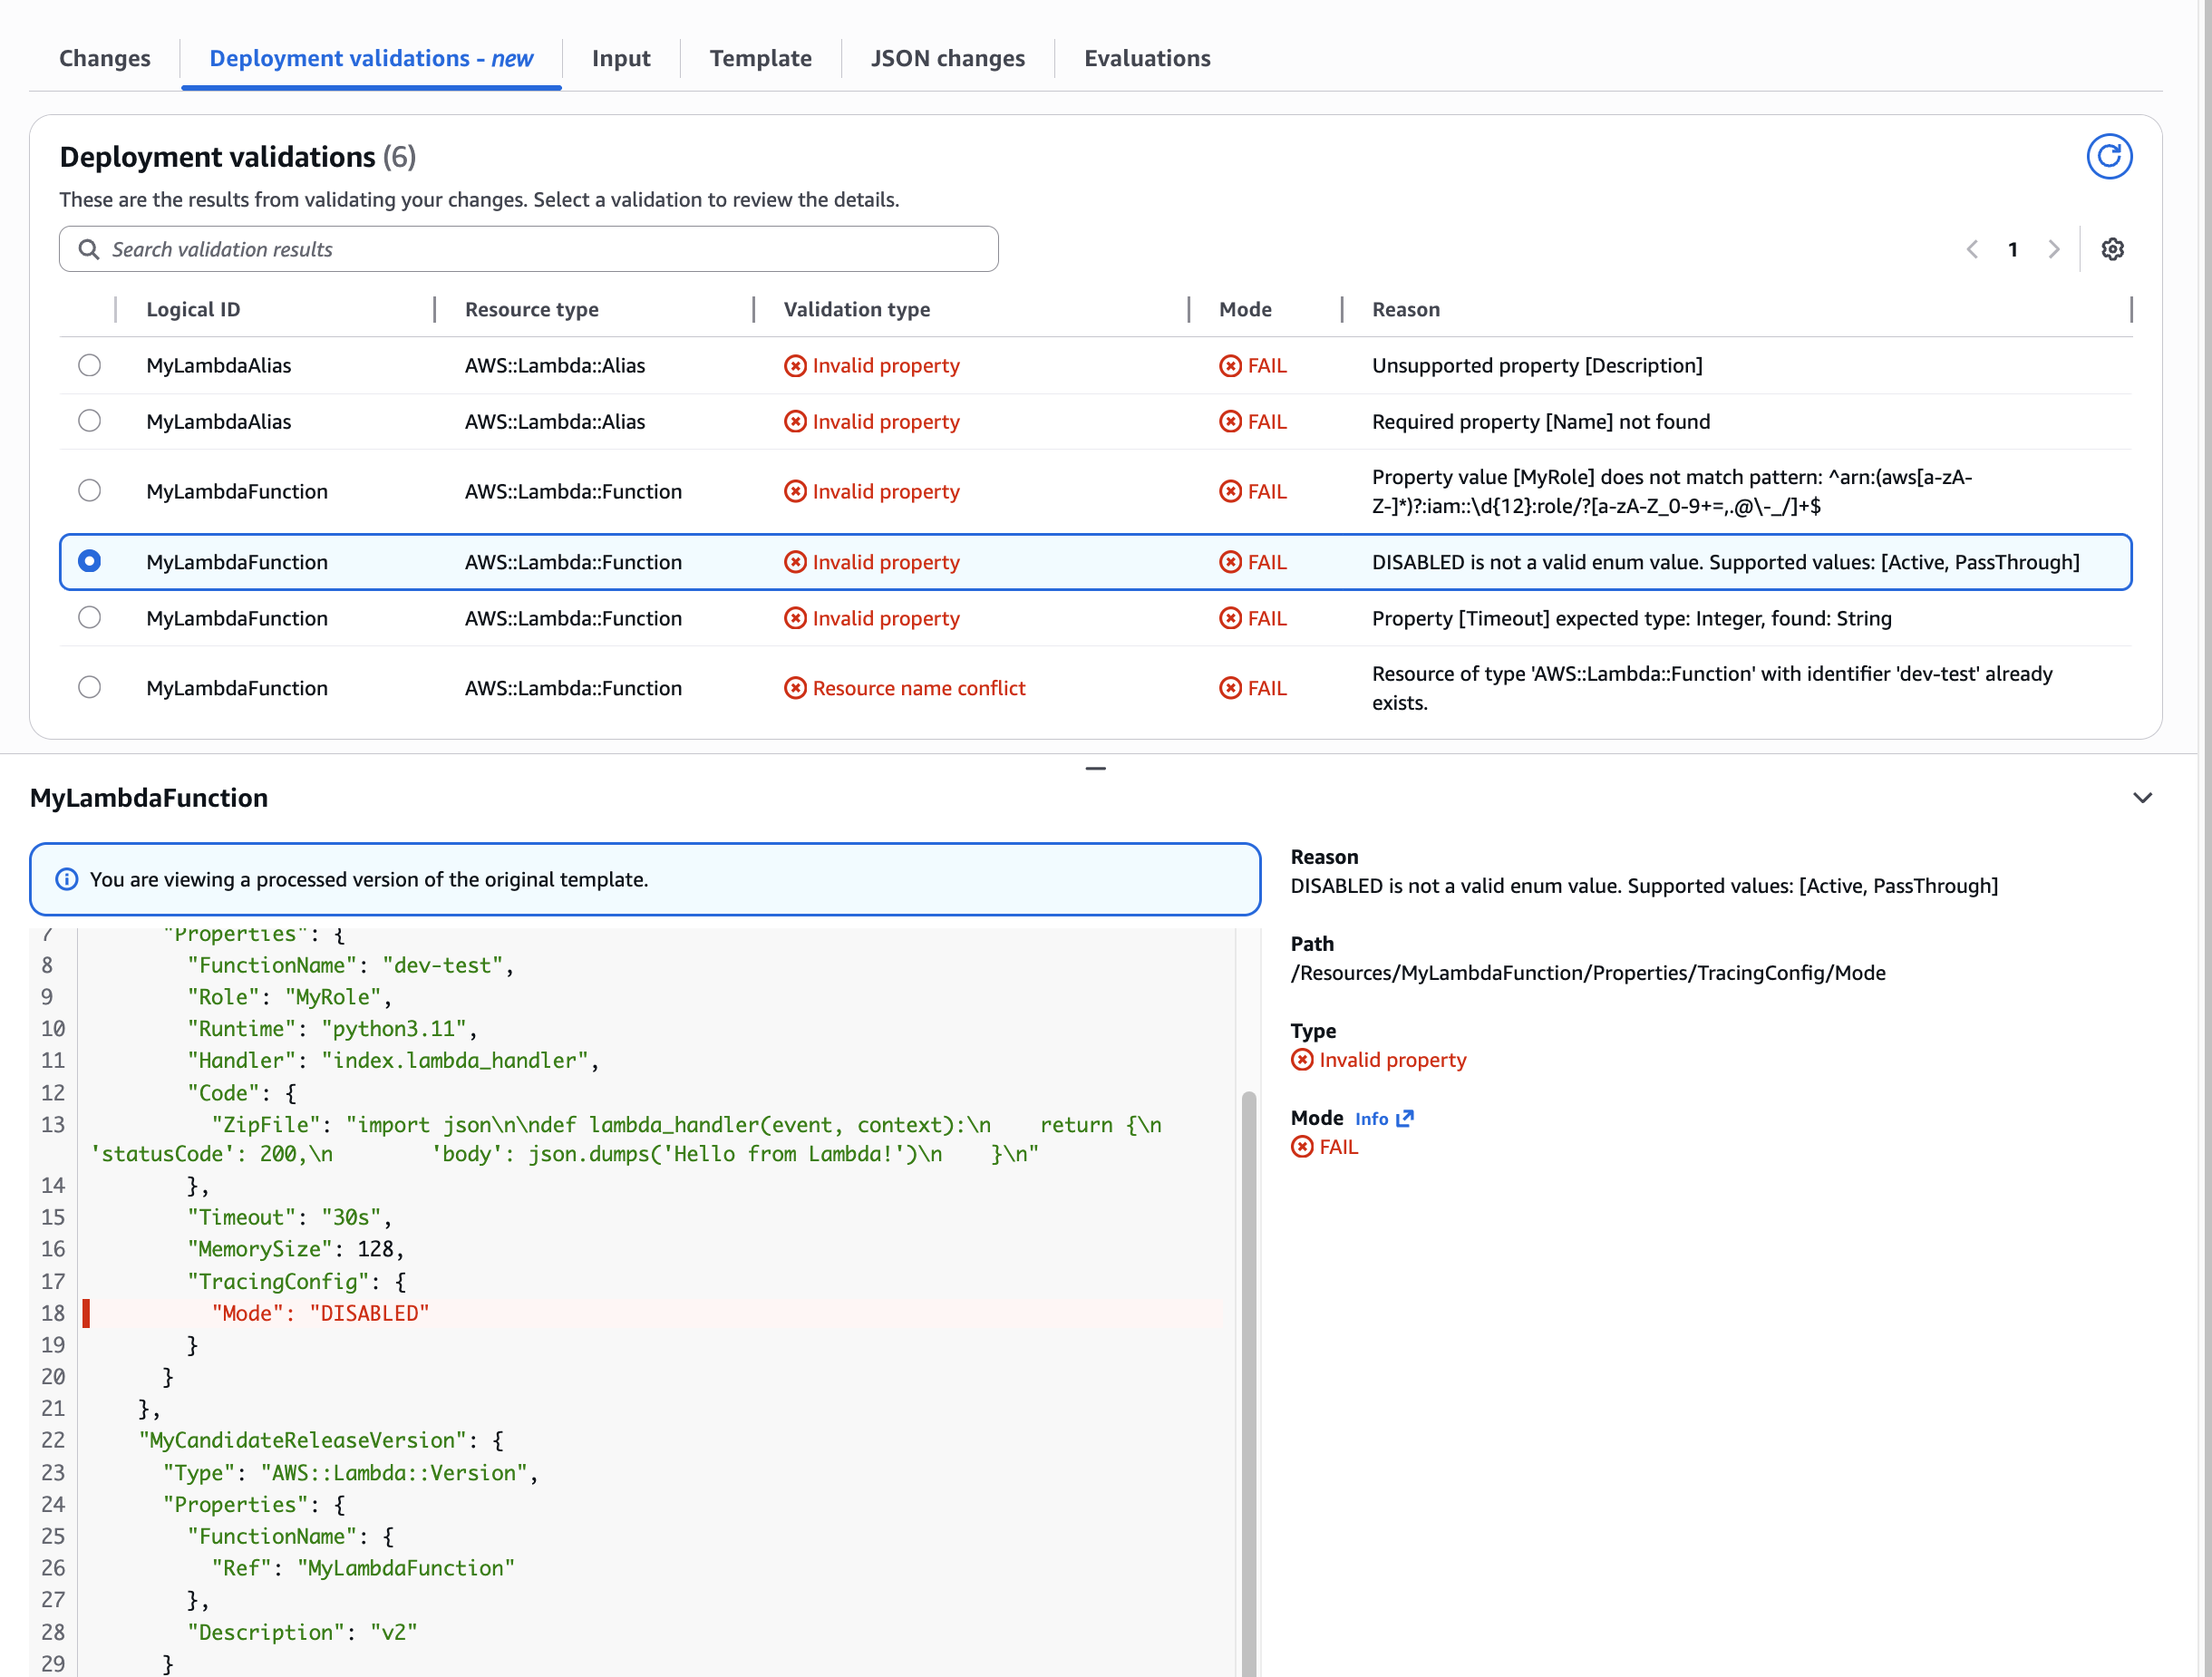
The deployment validation view below provide moe detail about the error, include status reason and path to the resource.

Figure 3 - Resource Name Conflict on UpdateStack Deployment validation

Figure 3: Resource Name Conflict on UpdateStack

Scenario 3: Service Quota Warning on CreateChangeSet

Service Quota validation is one of three new warning-mode validations available during change set creation. It checks whether creating or updating resources would exceed your AWS service quotas.

Create Change Set

aws cloudformation create-change-set \
    --stack-name "vpc-stack" \
    --change-set-name "add-subnets" \
    --template-body file://vpc-with-many-subnets.yaml

Validation output:

{
    "EventId": "3ba6f27b-4d3c-4e73-bac2-8d8cbf71a6d3",
    "StackId": "arn:aws:cloudformation:us-west-1:1234:stack/vpc-quota-test/492a84d0-73ee-11f1-a714-02e5a60ac85d",
    "OperationId": "b55e1e8f-28d1-4cbe-a6c3-59c92707e180",
    "OperationType": "CREATE_CHANGESET",
    "EventType": "VALIDATION_ERROR",
    "LogicalResourceId": "VPC1",
    "PhysicalResourceId": "",
    "ResourceType": "AWS::EC2::VPC",
    "Timestamp": "2026-06-29T19:11:12.727000+00:00",
    "ValidationFailureMode": "WARN",
    "ValidationName": "SERVICE_QUOTA_VALIDATION",
    "ValidationStatus": "FAILED",
    "ValidationStatusReason": "Service quota will be exceeded: AWS::EC2::VPC current usage 1/5, creating 6 would exceed limit",
    "ValidationPath": "/Resources/VPC1"
}

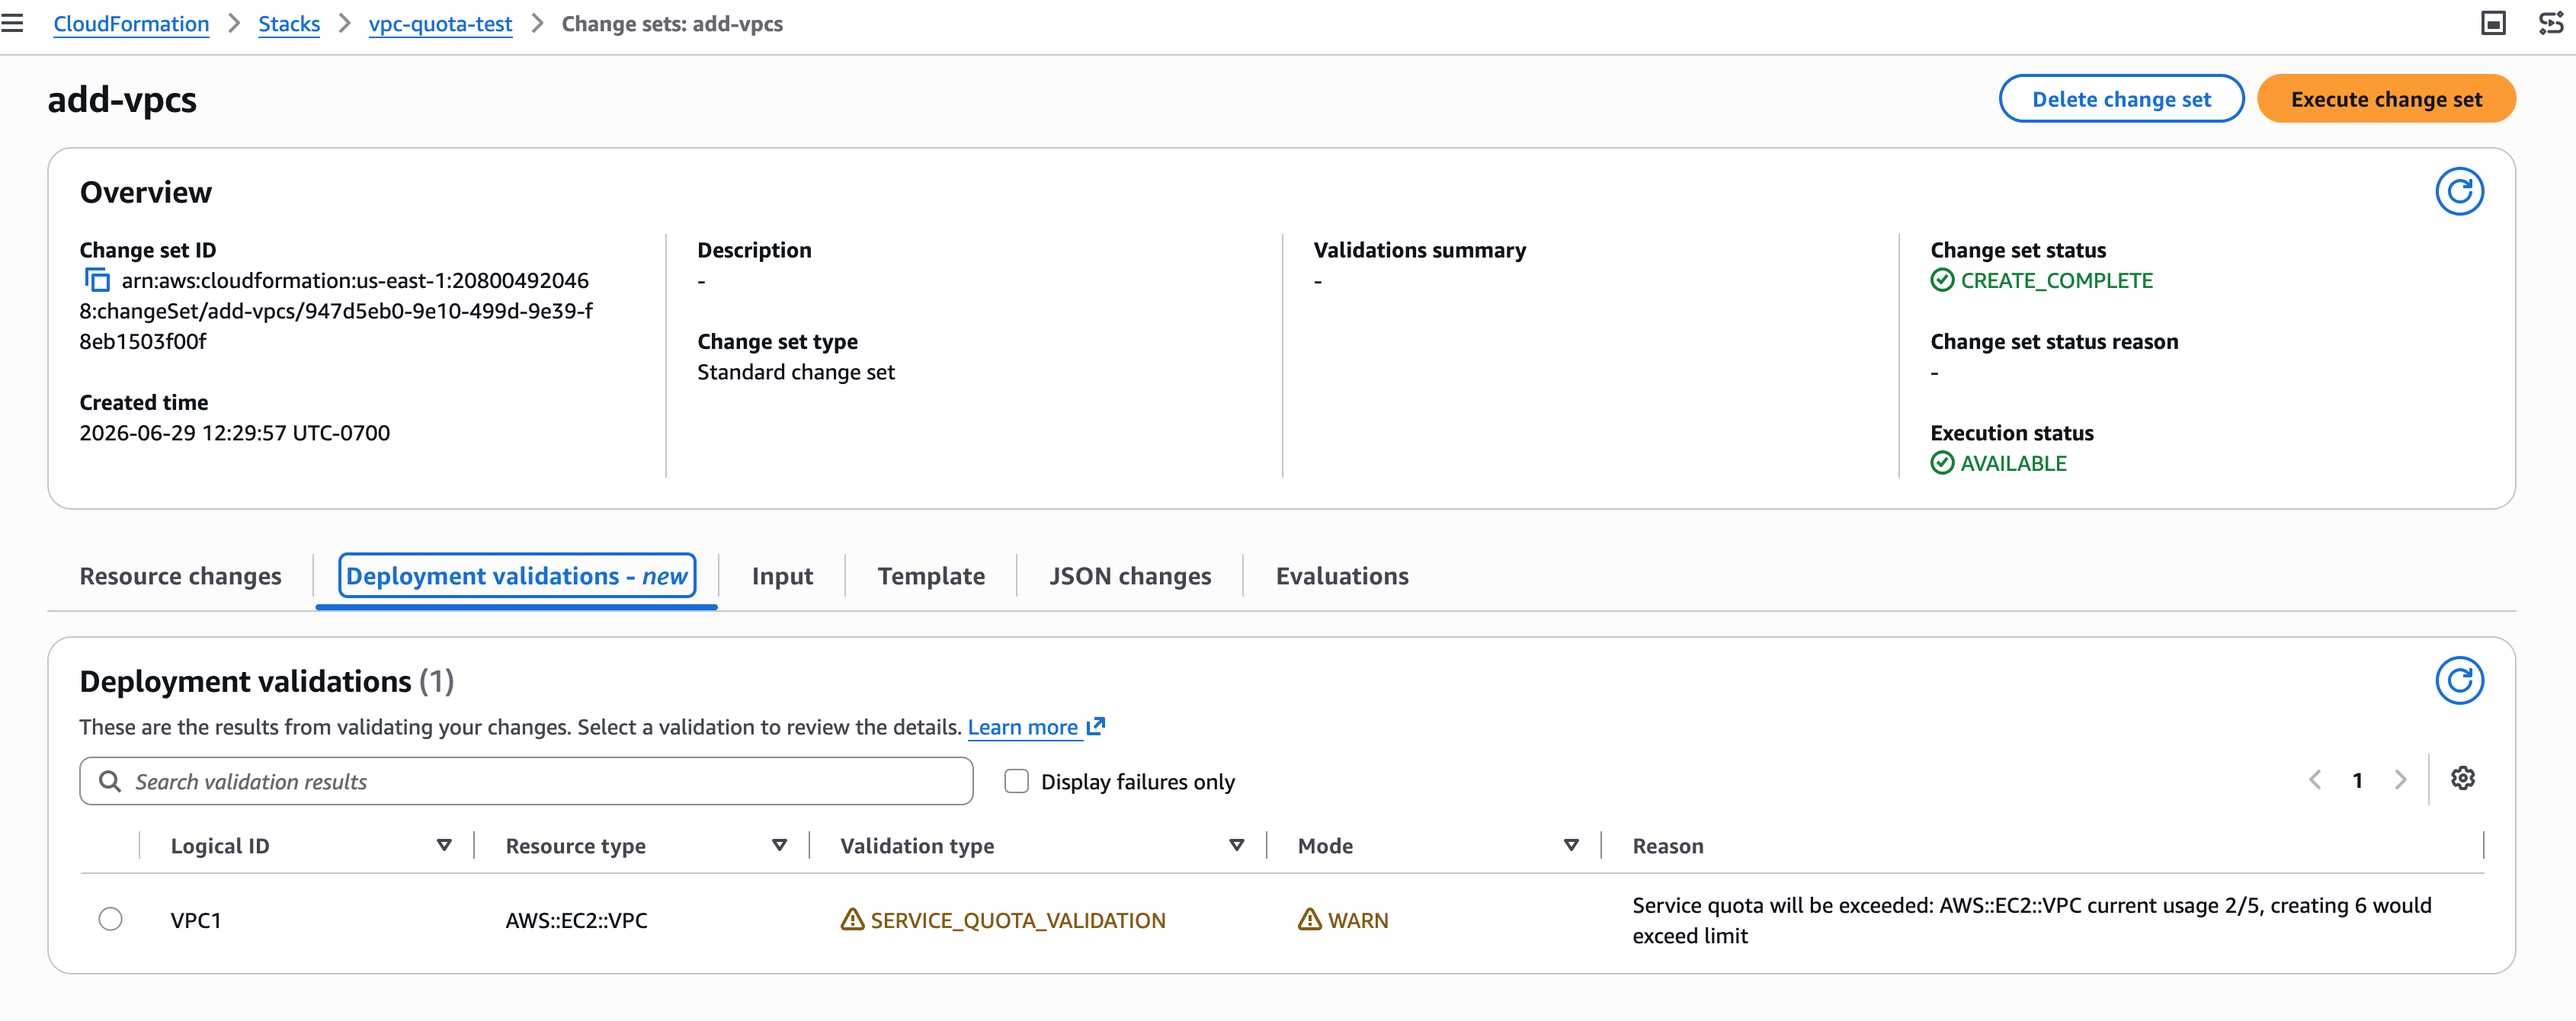
Because this validation operates in WARN mode, the change set is created successfully. You can review the warning, request a quota increase through the Service Quotas console, and then proceed with execution. The two other new warning validations (AWS Config Recorder conflict detection and ECR Repository delete readiness) follow the same pattern.

Figure 4 - Service Quotas Warning on CreateChangeSet

Figure 4: Service Quota Warning on CreateChangeSet

Scenario 4: CDK Validate Experience

The cdk validate command provides a unified validation experience that combines multiple validation sources into a single report with construct-level source tracing. Under the hood, cdk validate synthesizes your CDK app, creates a change set to invoke server-side pre-deployment validation, collects the results via DescribeEvents, and produces a report that maps errors back to your CDK source code with construct-level tracing.

Each error traces back to the specific construct and source file location in your CDK code, not just the CloudFormation logical resource ID. This construct-level tracing is what makes cdk validate uniquely valuable: you see the exact line in your code that needs to change.

Scenario 5: Controlling Validation with DisableValidation

Pre-deployment validation is enabled by default on all stack operations. If you need to skip validation for a specific operation, use the DisableValidation parameter.

When to disable validation:

  • When you have already validated your template through other means (cdk validate, cfn-lint, CI/CD checks)
  • When you need to minimize operation latency for time-sensitive deployments

CLI usage:

# Skip validation on create-stack
aws cloudformation create-stack \
    --stack-name "my-stack" \
    --template-body file://template.yaml \
    --disable-validation

# Skip validation on update-stack
aws cloudformation update-stack \
    --stack-name "my-stack" \
    --template-body file://template.yaml \
    --disable-validation

Important: Disabling validation means common errors will not be caught until resource provisioning is attempted. Use this option only when you understand the trade-off between deployment speed and early error detection.

AI Agents and Automated Workflows

Pre-deployment validation gives AI agents and automation tools the fast feedback loop they need to self-correct. When an agent provisions infrastructure and the template has an error, validation returns a structured error in seconds rather than waiting minutes for a full provision-and-rollback cycle to complete. The agent can parse the error, fix the template, and retry immediately.

With cdk validate, agents get construct-level source tracing that maps errors directly to the line of CDK code that needs to change, enabling fully automated fix-and-retry loops without human intervention.

To get started with the agent experience, install the CloudFormation agent skill from the AWS Agent Toolkit. This skill gives AI agents the ability to create stacks, validate templates, and iterate on errors using pre-deployment validation feedback.

Getting Started

Pre-deployment validation runs automatically on all CreateStack, UpdateStack, and CreateChangeSet operations with no configuration required. To start benefiting:

  • Create or update a stack as you normally would. Validation runs automatically.
  • Review validation results using the DescribeEvents API, the CloudFormation Console Events tab (click the operation ID, then the Deployment validations tab), or the cdk validate command.
  • Fix identified issues in your template and retry the operation.
  • Optionally disable validation using --disable-validation for specific operations

Required IAM permissions for validation checks

Validation on CreateStack and UpdateStack (property syntax validation and resource name conflict detection) requires no additional IAM permissions beyond what is needed for the stack operation itself. For the new validation checks available during change set creation, your IAM role needs the following additional permissions:

Service Quota Check:

  • cloudwatch:GetMetricData
  • lambda:GetAccountSettings
  • servicequotas:GetServiceQuota
  • ec2:DescribeSecurityGroups
  • iam:GetAccountSummary

Config Recorder Check:

  • config:ListConfigurationRecorders

S3 Bucket Empty Check:

  • s3:ListBucketV2

ECR Repository Delete Readiness Check:

  • ecr:ListImages

If these permissions are not granted, the corresponding validation checks will be skipped without blocking the operation.

For CDK users:

# Run unified validation before deploying 
cdk validate

Best Practices

  • Use cdk validate as your primary pre-deployment check. It leverages CloudFormation pre-deployment validation in a single command, giving you comprehensive coverage before any deployment is attempted.
  • Place CreateChangeSet as the first pipeline stage. For pipelines that use change sets, this ensures pre-deployment validation fires at the pipeline entry point. CDK Pipelines integrates this by default.
  • Let validation run by default. The few seconds of validation time pay for themselves by preventing full provision-and-rollback cycles that take minutes or longer.
  • Use DisableValidation intentionally. Reserve it for cases where you have already validated through other means or need to bypass a known false positive. Do not disable validation globally.
  • Integrate validation into PR/CI workflows. Run cdk validate or cfn-lint as part of your pull request checks to catch errors before code is merged, preventing invalid templates from reaching deployment pipelines.
  • Monitor validation warnings. WARN-mode validations (service quota, Config Recorder, ECR delete readiness) indicate potential issues that may cause failures at execution time. Address them proactively.

Conclusion

Pre-deployment validation on all stack operations represents a significant step forward in CloudFormation’s shift-left validation strategy. By catching common deployment errors in seconds before any resources are provisioned, this capability eliminates unnecessary rollback cycles and accelerates development workflows across the board.

Combined with the cdk validate command, which provides a unified validation experience with construct-level tracing, and the DisableValidation parameter for operation-level control, teams now have a complete toolkit for managing the trade-off between validation coverage and deployment speed. AI agents and automated pipelines benefit from structured, machine-readable feedback that enables immediate self-correction, turning what were once multi-minute debugging cycles into second-level iteration loops.

Pre-deployment validation is available in all AWS Regions where CloudFormation is supported. No configuration or opt-in is required. To learn more, visit the Validate stack deployments User Guide.

Blog Authors Bio:

Idriss Laouali Abdou

Idriss is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Olivia Biswas

Olivia is a Software Development Manager on the AWS Infrastructure-as-Code team based in Seattle, where she leads developer productivity initiatives through CloudFormation. During her tenure at Amazon, she has built several customer-obsessed software solutions within Alexa and Buy With Prime. Outside of work, she is a globe trotter who enjoys baking, dancing, reading, and watching documentaries.

Subha Velayutham

Subha is a Senior Software Engineer on the AWS Infrastructure-as-Code team, where she builds features to improve developer productivity. Outside of work, she enjoys reading, traveling, and experimenting with new creative hobbies.

Accelerate your infrastructure deployments by up to 4x with AWS CloudFormation Express mode

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/accelerate-your-infrastructure-deployments-by-up-to-4x-with-aws-cloudformation-express-mode/

Today, we’re announcing AWS CloudFormation Express mode, a new deployment mode that accelerates deployments for developers and AI tools iterating on infrastructure. Express mode accelerates deployments by completing when CloudFormation confirms resource configuration is applied, rather than waiting for extended stabilization checks. This reduces deployment time by up to 4 times for iterative development workflows and production scenarios.

How it works
Every CloudFormation deployment performs stabilization checks after resource configuration is applied. These checks serve an important purpose when you need to confirm resources can serve traffic before shifting load.

However, many workflows do not require full stabilization to proceed. Express mode benefits two primary use cases: iterative development workflows and production scenarios where you are comfortable with eventual stabilization. These use cases include iterating on infrastructure configurations during development, testing individual components of your application, and AI-assisted infrastructure development that benefits from sub-minute feedback loops.

With Express mode, CloudFormation completes deployments when resource configuration is applied, without waiting for stabilization checks. Resources continue becoming operational in the background. CloudFormation automatically retries dependent resources that encounter transient failures during provisioning within the same stack, without requiring any customer intervention. This built-in resilience handles timing issues between resources as they stabilize. Express mode changes when the deployment completes, not how resources are provisioned.

For example, when I create an Amazon Simple Queue Service (SQS) queue with a dead letter queue (DLQ), Standard mode takes 64 seconds, but Express mode completes in up to 10 seconds. In the case of deleting an AWS Lambda function with network interface attachment, Standard mode takes 20–30 minutes, but Express mode completes in up to 10 seconds based on my benchmarking test.

Get started with CloudFormation Express mode
When you create a CloudFormation stack in the AWS Management Console, choose Enable in the Express mode under Stack deployment options.

You can also use AWS Command Line Interface (AWS CLI), AWS SDKs, or IaC tools like AWS Cloud Development Kit (CDK), and AI tools such as Kiro.

Activate Express mode by setting the --deployment-config parameter to EXPRESS when creating, updating, or deleting stacks. No template changes are required. Express mode disables rollback by default for the fastest iteration experience. To re-enable rollback, set disableRollback to false in the deployment-config for production environments, or implement monitoring/cleanup mechanisms for failed deployments.

aws cloudformation create-stack \ 
   --stack-name my-app \ 
   --template-body file://template.yaml \ 
   --deployment-config '{"mode": "EXPRESS", "disableRollback": true}' \

For example, use the Express mode when you build infrastructure incrementally, adding resources one at a time. Ensure your IAM role templates follow the principle of least privilege.

# Iteration 1: Deploy IAM role
aws cloudformation create-stack \
--stack-name my-microservice \
--template-body file://iteration1-iam.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

# Iteration 2: Add Lambda function
aws cloudformation update-stack \
--stack-name my-microservice \
--template-body file://iteration2-lambda.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

# Iteration 3: Add SQS queue and event source mapping
aws cloudformation update-stack \
--stack-name my-microservice \
--template-body file://iteration3-sqs.yaml \
--deployment-config '{"mode": "EXPRESS"}' \
--capabilities CAPABILITY_IAM
--role-arn arn:aws:iam::123456789012:role/CloudFormationDeployRole

For AWS CDK, activate Express mode with the cdk deploy --express command when you deploy your CDK stack. This command retrieves your generated CloudFormation template and deploys it through the CloudFormation Express mode, which provisions your resources as part of a CloudFormation stack.

Express mode works with all existing CloudFormation templates and supports all CloudFormation features including change sets and nested stacks. When you enable Express mode on a parent stack, all nested stacks also use Express mode. If you need resources to be fully operational before proceeding with traffic or testing, continue using the default deployment behavior, which performs stabilization checks before completing.

Now available
AWS CloudFormation Express mode is available today in all AWS commercial Regions at no additional cost. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this new feature, try using the AWS MCP Server and plugins with your preferred AI tool. To learn more, visit the CloudFormation documentation.

Start accelerating your deployments today, and send feedback to AWS re:Post for AWS CloudFormation or through your usual AWS Support contacts.

Channy

Automating identity lifecycle and security with AWS Directory Service APIs

Post Syndicated from Ali Alzand original https://aws.amazon.com/blogs/security/automating-identity-lifecycle-and-security-with-aws-directory-service-apis/

Managing identities and access across complex environments has become more critical than ever. AWS Directory Service for Managed Microsoft Active Directory, also known as AWS Managed Microsoft AD, has added new capabilities to manage users and groups. Now, you can perform create, read, update, and delete (CRUD) operations on users and groups directly through AWS Command Line Interface (AWS CLI), APIs, and the AWS Management Console. You can use this powerful capability to automate identity lifecycle management and enhance security in your AWS environment. By using these APIs, collectively known as the Directory Service Data APIs, you can perform operations such as:

  • Listing users and groups
  • Retrieving user and group details
  • Disabling and enabling user accounts
  • Resetting user passwords
  • Managing group memberships

These APIs provide new possibilities for automating identity management tasks and integrating Active Directory management into your existing workflows and applications.

The introduction of these APIs brings several key benefits:

  • Automation of the identity lifecycle: You can now programmatically manage user accounts throughout their lifecycle—from creation to deletion—enabling streamlined onboarding and offboarding processes.
  • Enhanced security: By integrating these APIs with security services like Amazon GuardDuty, you can create automated responses to potential security threats, such as disabling accounts with inappropriate access.
  • Improved compliance: You can use automated user management to help enforce consistent policies and help maintain compliance with various regulatory requirements.
  • Operational efficiency: You can automate routine tasks such as user provisioning, deprovisioning, and group management, reducing manual effort and the potential for human error.
  • Integration capabilities: By using these APIs, you can seamlessly integrate with existing identity management systems, custom applications, and third-party tools.
  • Cost optimization: By automating processes and reducing manual intervention, you can potentially help your organization optimize operational costs associated with identity management.

In this post, we explore these new APIs and demonstrate how you can use them to create an automated solution for detecting and responding to unexpected behavior by Active Directory users. We walk through a practical example that combines GuardDuty, AWS Step Functions, Amazon EventBridge, and the new AWS Directory Service APIs to create a robust security automation workflow.

Solution overview

To demonstrate the power of these new APIs, let’s explore a practical solution that automates the detection and response to unexpected behavior by Active Directory users. This solution combines several AWS services to create a robust security automation workflow:

    1. GuardDuty continuously monitors for unexplained behavior of Active Directory users from AWS Managed Microsoft AD. For the example in this post, we’re using Backdoor:Runtime/C&CActivity.B!DNS
    2. An EventBridge rule detects GuardDuty findings related to these users and triggers a Step Functions workflow.
      {
        "detail-type": ["GuardDuty Finding"],
        "source": ["aws.guardduty"],
        "detail": {
          "type": ["Backdoor:Runtime/C&CActivity.B!DNS"]
        }
      }

    3. The Step Functions workflow will:
      1. Extract the Active Directory username from the instance using a run command.
      2. Start an automation that will disable the account using the DisableUser API.
Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

  1. Finally, another EventBridge rule will monitor the DisableUser API call. It will send an email to the user using Amazon Simple Notification Service (Amazon SNS) notifications.
    {
      "detail-type": ["AWS API Call via CloudTrail"],
      "source": ["aws.ds"],
      "detail": {
        "eventSource": ["ds.amazonaws.com"],
        "eventName": ["DisableUser"]
      }
    }

This solution delivers automated, near real-time remediation of potential security threats — significantly reducing exposure windows and containing the impact of unauthorized account access.

The following figure shows a high-level architecture diagram of the solution.

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Note: The solution must be deployed in the primary AWS Region of your directory.

Prerequisites

To complete the walkthrough in this post, you must have the following prerequisites in place.

GuardDuty

GuardDuty is an automated threat detection service that continuously monitors for unexpected activity and unauthorized behavior to protect your AWS accounts, workloads, and data stored in Amazon Simple Storage Service (Amazon S3).

To activate GuardDuty:

  1. Go to the GuardDuty console.
    1. If you’re activating GuardDuty for the first time, under Try threat detection with GuardDuty, select All Features and then choose Get Started.
    2. If you’ve used GuardDuty before, select Runtime Monitoring and then choose Enable under Runtime Monitoring.
Figure 3: Runtime Monitoring enabled

Figure 3: Runtime Monitoring enabled

AWS Managed Microsoft AD

AWS Managed Microsoft AD provides a fully managed service for Microsoft Active Directory (AD) in the AWS Cloud. When you create your directory, AWS deploys two domain controllers that are exclusively yours in separate Availability Zones for high availability. For use cases that require even higher resilience and performance in a specific AWS Region or during specific hours, you can scale AWS Managed Microsoft AD by deploying additional domain controllers to meet your needs. These domain controllers can help load balance, increase overall performance, or provide additional nodes to protect against temporary availability issues. Using AWS Managed Microsoft AD, you can define the correct number of domain controllers for your directory based on your use case.

To deploy a new AWS Managed Microsoft AD:

  1. Go to the Directory Service console.
  2. Choose Set up directory and select AWS Managed Microsoft AD.
  3. Select Standard Edition and enter a directory DNS name and password.
  4. Select a virtual private cloud (VPC). For this example, use the Default VPC.
  5. Choose Create directory.

Create a test Active Directory user

You will use this test user account to sign in to an EC2 instance and initiate a command that simulates unexplained activity that results in this account being disabled.

To create the test user, you can use AWS CloudShell or the AWS CLI from your local machine. Run the following commands, replacing the --directory-id value with your own:

# Create the test user
aws ds-data create-user \
 --directory-id "your-directory-id" \
 --sam-account-name "TestUser" \
 --given-name "Test" \
 --surname "User"

Then

# Set a password for the test user 
aws ds reset-user-password \
 --directory-id "your-directory-id" \
 --user-name "TestUser" \
 --new-password "YourSecurePassword123!"

In this example, the password is set to YourSecurePassword123!. If you need to replace it with a password that meets your organization’s requirements, see Resetting and enabling an AWS Managed Microsoft AD user’s password. For more information on creating users, see Creating an AWS Managed Microsoft AD user in the AWS Directory Service documentation.

Test EC2 instance

To generate alerts on GuardDuty, you need a domain joined Linux EC2 instance. If you don’t have a domain joined EC2 Linux instance, follow these instructions for joining a Linux instance to an Active Directory domain. This instance will be used to simulate suspicious activity that triggers a GuardDuty finding and initiates the automated remediation workflow.

Implement the solution

Let’s walk through the steps to implement this solution in your AWS environment.

Deploy the solution

  1. Download the CloudFormation template
  2. Navigate to the CloudFormation console in the AWS account.
  3. For Create Stack, choose with new resources (standard).
  4. For Template source, choose Upload a template file. Choose Choose file and select the template you downloaded in step 1.
  5. Choose Next.
  6. For Stack name, enter a stack name (such as CRUD-API-MAD).
  7. In the Parameters area, do the following:
    1. For DirectoryID, enter the AWS Active Directory ID.
    2. For NotificationEmail, enter the email address to send the notification to.
  8. On the Configure stack options page, choose Next.
  9. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.

After the page is refreshed, the status of your stack should be CREATE_IN_PROGRESS. When the status changes to CREATE_COMPLETE, proceed to the next section.

Test

To simulate a threat, use a GuardDuty test domain that GuardDuty will recognize as a command and control server.

  1. Go to the Amazon EC2 console.
  2. Choose Instances from the navigation pane.
  3. Select the test EC2 instance that you created earlier.
  4. Choose Connect, select the Session Manager tab, and choose Connect.
  5. Authenticate with your test user by entering su followed by the test user with the domain name that you created earlier. For example su [email protected], then enter the password.
  6. Enter the command curl guarddutyc2activityb.com.
    You will receive an error because the page won’t resolve, but GuardDuty will have detected concerning events.
  7. Go to the GuardDuty console and select Findings from the navigation pane.
  8. Within 3–5 minutes, you should see a high severity finding for Backdoor:Runtime/C&CActivity.B!DNS.
  9. This will then trigger the automation to disable the account.
    Figure 4: Account successfully disabled

    Figure 4: Account successfully disabled

  10. After the account is disabled, an email notification will be sent notifying an administrator that the account was disabled (it might take up to 5 minutes to receive the notification).

    Figure 5: AWS notification message showing the username has been disabled

    Figure 5: AWS notification message showing the username has been disabled

Note: You must archive the GuardDuty finding before running this test again, because the EventBridge rule only runs once against a GuardDuty finding with the same details. To archive the finding, select the check box next to the Backdoor:Runtime/C&CActivity.B!DNS finding, choose Actions (top right), and select Archive.

Conclusion

The new AWS Directory Service APIs for AWS Managed Microsoft AD provide powerful capabilities for programmatically managing Active Directory users and groups. By using these APIs in conjunction with services such as Amazon GuardDuty and AWS Step Functions, you can create sophisticated automation workflows that enhance your security posture and streamline identity management processes.

The solution we’ve explored in this post demonstrates just one of many possible use cases for these new APIs. As you integrate these capabilities into your own environments, you will probably discover numerous opportunities to improve efficiency, security, and compliance in your identity management practices.

For a solution that uses PowerShell Active Directory cmdlets with AWS Systems Manager Run Command to disable users, see How to automatically disable users in AWS Managed Microsoft AD based on GuardDuty findings.

For more information about AWS Directory Service and its APIs, visit the AWS Directory Service documentation.

We’re excited to see how you’ll use these new APIs to innovate and improve your identity management workflows. If you have any questions or want to share your own use cases, leave a comment below or reach out to AWS Support.

Remember, the cloud journey is all about continuous improvement and innovation. Keep exploring, keep learning, and keep pushing the boundaries of what’s possible with AWS.

Ali Alzand

Ali Alzand

Ali is a Senior Infrastructure Migration & Modernization Specialist Solutions Architect at AWS who helps enterprise customers migrate, modernize, and operate their Microsoft workloads on AWS. He specializes in Infrastructure as Code, automating at scale with AWS Systems Manager, EC2 Image Builder, and CloudFormation. He also designs event-driven architectures building responsive, loosely coupled solutions with EventBridge and Lambda. Outside of work, Ali enjoys grilling with friends and discovering new cuisines around town.

Kevin Sookhan

Kevin Sookhan

Kevin is a Specialist Solutions Architect at Amazon Web Services with over 20 years of experience working with Microsoft technologies. He has expertise in running Microsoft workloads on AWS with specialization in helping customers with their migrations, cost optimization, and infrastructure architecture.

Simplify cross-account and cross-Region stack output references with AWS CloudFormation and CDK’s new Fn::GetStackOutput

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/simplify-cross-account-and-cross-region-stack-output-references-with-aws-cloudformation-and-cdks-new-fngetstackoutput/

AWS CloudFormation makes it easy to model and provision your cloud application infrastructure as code. CloudFormation templates can be written directly in JSON or YAML, or they can be generated by tools like the AWS Cloud Development Kit (CDK). Resources are created and managed by CloudFormation as units called Stacks.

Managing infrastructure across multiple AWS accounts and Regions is a common pattern for organizations adopting AWS best practices like multi-account strategies. However, sharing infrastructure values, such as VPC IDs, subnet configurations, or database endpoints, between stacks in different accounts or Regions has historically required multiple manual steps. Today, we’re excited to announce Fn::GetStackOutput, a new CloudFormation intrinsic function that lets you reference stack outputs across accounts and Regions directly in your CloudFormation templates and AWS CDK applications.

In this post, we walk through how Fn::GetStackOutput works in both CloudFormation and CDK, compare it with the existing Fn::ImportValue approach, and show you how to get started with practical examples.

The challenge: sharing values across accounts and Regions

When building multi-account AWS environments, teams frequently need to share infrastructure values across organizational boundaries. For example:

  • A networking team maintains a shared VPC in a central account, and application teams in other accounts need to reference the VPC ID.
  • A security team deploys shared security groups, and workload accounts need to consume them.
  • A platform team provisions foundational resources in one Region, and teams deploying in other Regions need those values.

Previously, you had two options:

  1. Fn::ImportValue with exports worked well within the same account and Region but did not support cross-account or cross-Region references.
  2. Manual approaches such as copying values between templates, passing parameters through CI/CD pipelines, or maintaining custom automation to keep values in sync.

Both approaches added operational overhead and increased the risk of configuration drift when values changed.

Introducing Fn::GetStackOutput

Fn::GetStackOutput is a new CloudFormation intrinsic function that resolves stack output references at deployment time. It provides two key advantages over the existing export/import model:

  1. Cross-account and cross-Region support. You can reference outputs from stacks in any account and Region (within the same partition).
  2. No exports required. You can reference any stack output directly, without the producing stack needing to declare an Export.

How it works

When CloudFormation processes a template containing Fn::GetStackOutput, it:

  1. Identifies the referenced stack and output.
  2. If a RoleArn is specified, assumes that role to access the target account.
  3. Calls DescribeStacks to retrieve the output value from the specified stack and Region.
  4. Resolves the value and continues template processing.

The function accepts four parameters:

  • StackName (required): The name of the stack that contains the output you want to reference.
  • OutputName (required): The logical ID of the output to reference. This is the key defined in the Outputs section of the referenced stack’s template, not an export name.
  • Region (optional): The AWS Region where the referenced stack is deployed. Defaults to the Region of the stack being created or updated.
  • RoleArn (optional): The ARN of an IAM role with cloudformation:DescribeStacks permissions on the referenced stack. Use this parameter when referencing a stack in a different AWS accoun

Walkthrough: four scenarios

Let’s walk through a practical example. Suppose you have a networking stack that creates a VPC:

`# ProducerStack - deployed in us-west-2, account 111111111111
Resources:
  MyVPC:
    Type: AWS::EC2::VPC
    Properties:
      CidrBlock: 10.0.0.0/16
Outputs:
  VpcId:
    Value: !Ref MyVPC 
`

Now let’s see how to reference this VPC ID from different stacks.

Scenario 1: Same account, same Region

The simplest case. Both stacks are in us-west-2 in account 111111111111:

`Resources:
  MyInstance:
    Type: AWS::EC2::Instance
    Properties:
      VpcId:
        Fn::GetStackOutput:
          StackName: ProducerStack
          OutputName: VpcId
`

No Region or RoleArn needed. CloudFormation uses the current stack’s Region and execution role.

Scenario 2: Same account, different Region

Your consumer stack is in us-east-1, but the VPC is in us-west-2:

`Resources:
  MyInstance:
    Type: AWS::EC2::Instance
    Properties:
      VpcId:
        Fn::GetStackOutput:
          StackName: ProducerStack
          OutputName: VpcId
          Region: us-west-2
`

The Region parameter tells CloudFormation where to find the referenced stack.

Scenario 3: Different account, same Region

Your consumer stack is in account 222222222222, and the VPC is in account 111111111111:

`Resources:
  MyInstance:
    Type: AWS::EC2::Instance
    Properties:
      VpcId:
        Fn::GetStackOutput:
          StackName: ProducerStack
          OutputName: VpcId
          RoleArn: arn:aws:iam::111111111111:role/GetStackOutputRole
`

The RoleArn specifies a role in the producer account with cloudformation:DescribeStacks permissions.

Scenario 4: Different account and different Region

Combine both parameters for the most flexible scenario:

`Resources:
  MyInstance:
    Type: AWS::EC2::Instance
    Properties:
      VpcId:
        Fn::GetStackOutput:
          StackName: ProducerStack
          OutputName: VpcId
          RoleArn: arn:aws:iam::111111111111:role/GetStackOutputRole
          Region: us-west-2
`

Setting up IAM for cross-account access

When referencing stacks in other accounts, the IAM role specified in RoleArn needs cloudformation:DescribeStacks permissions:

`{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["cloudformation:DescribeStacks"],
      "Resource": "*"
    }
  ]
}
`

For a more restrictive policy, scope the Resource to the specific stack ARN you want to reference.

The IAM role should be assumable by your consumer stack’s execution role. For this example, we’ll grant generic access to account 222222222222 in the trust policy:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "AWS": "222222222222"
            },
            "Action": "sts:AssumeRole"
        }
    ]
}

Fn::GetStackOutput vs. Fn::ImportValue

If you’re already using Fn::ImportValue, you may be wondering when to use which. Here’s a comparison:

Fn::ImportValue:

  • Same account, same Region: Supported
  • Cross-account: Not supported
  • Cross-Region: Not supported
  • Requires explicit Export: Yes
  • Reference type: Strong — blocks deletion of the exporting stack
  • Referential integrity: Yes

Fn::GetStackOutput:

  • Same account, same Region: Supported
  • Cross-account: Supported
  • Cross-Region: Supported
  • Requires explicit Export: No
  • Reference type: Weak — resolved at stack create or update time
  • Referential integrity: No

Use Fn::ImportValue when you need strong referential integrity within the same account and Region. CloudFormation prevents you from deleting a stack that exports values consumed by other stacks.

Use Fn::GetStackOutput when you need cross-account or cross-Region references, or when you want to avoid managing explicit exports.

Understanding weak references

An important difference to understand: Fn::GetStackOutput creates weak references. This means:

  • The referenced stack doesn’t know it’s being referenced. Unlike exports, there is no dependency tracking between the producer and consumer stacks.
  • Deleting the producer stack is not blocked. If you delete the producer stack or remove the referenced output, CloudFormation does not prevent you. However, the next time the consumer stack is created or updated, the operation will fail because the reference can no longer be resolved. Because of this, deleting the producer stack may cause impact in the consumer stack.
  • Changes are not automatically propagated. If the output value changes in the producer stack, the consumer stack is not automatically updated. You need to run an update on the consumer stack to pick up the new value.

Best practices for weak references

  • Enable deletion protection on producer stacks that other stacks depend on.
  • Use stack policies to prevent accidental modifications to critical outputs.
  • Document dependencies between stacks so teams are aware of cross-stack relationships.
  • Scope IAM roles narrowly by restricting DescribeStacks permissions to specific stack ARNs when possible.

Using Fn::GetStackOutput with AWS CDK

CDK now uses Fn::GetStackOutput to automatically resolve cross-region and cross-account references in the same app. Previously, this required opting in through the crossRegionReferences Stack parameter.

Here’s an example of how cross-account references work in CDK:

class Provider extends Stack {
  public readonly vpc: ec2.Vpc;

  constructor(scope: Construct, id: string, props: StackProps) {
    super(scope, id, props);
    this.vpc = new ec2.Vpc(this, 'MyVpc', { maxAzs: 2 }); 
  }
}

interface ConsumerProps extends StackProps {
  readonly vpc: ec2.IVpc;
}

class Consumer extends Stack {
  constructor(scope: Construct, id: string, props: ConsumerProps) {
    super(scope, id, props);
    new ec2.SecurityGroup(this, 'MySG', {
      vpc: props.vpc,
      description: 'SG in Consumer using VPC from Provider',
    }); 
  }
}

const app = new App({
  context: {
    // choice between 'strong', 'weak', or 'both'
    '@aws-cdk/core:defaultCrossStackReferences': 'weak',
  },
});

const provider = new Provider(app, 'Provider', {
  env: { account: '111111111', region: 'us-west-2' },
});

new Consumer(app, 'Consumer', {
  env: { account: '111111111', region: 'us-west-2' },
  vpc: provider.vpc,
});

The CDK synthesizes this into a template using Fn::GetStackOutput with no additional configuration required from the user. Since this is a cross-account reference, CDK will also generate a new IAM role that can be assumed by the consumer stack.

In case of same account, cross-region, or same account and region, you can tell the CDK whether to generate strong or weak references, using the @aws-cdk/core:defaultCrossStackReferences context key. Here is how it works:

  • Flag=strong (default when unset):
    • Same account and Region: generates a Fn::ImportValue reference
    • Same account, cross-Region: generates an ExportWriter/ExportReader pair (legacy custom resources)
    • Cross-account: not possible, falls back to weak
  • Flag=both:
    • Same account and Region: generates a Fn::GetStackOutput reference and an Export, but not Fn::ImportValue
    • Same account, cross-Region: generates a Fn::GetStackOutput reference and an ExportWriter, but not the ExportReader
    • Cross-account: generates a Fn::GetStackOutput reference and a cross-account IAM role
  • Flag=weak:
    • Same account and Region: generates a Fn::GetStackOutput reference
    • Same account, cross-Region: generates a Fn::GetStackOutput reference
    • Cross-account: generates a Fn::GetStackOutput reference and a cross-account IAM role

You can also resolve cross-region or cross-account references between stacks in different CDK Applications explicitly using the Fn.getStackOutput() method. For more information, see the CDK documentation.

Getting started

To start using Fn::GetStackOutput:

  1. Output the value you want to reference. See CloudFormation template Outputs syntax to understand declaring an output.
  2. For cross-account references, create an IAM role in the producer account with cloudformation:DescribeStacks permissions.
  3. Add the function to your template. Use the Fn::GetStackOutput syntax with the appropriate parameters.
  4. Deploy your stack. CloudFormation resolves the reference during the create or update operation.

Conclusion

Fn::GetStackOutput simplifies multi-account and multi-Region infrastructure management by enabling direct references between stacks without requiring explicit exports or custom workarounds. Whether you’re using CloudFormation templates directly or building with the AWS CDK, this new capability reduces operational overhead and the risk of configuration drift across your organization.

This feature is available in all AWS Regions where CloudFormation is supported. To learn more, visit the Fn::GetStackOutput documentation in the CloudFormation Template Reference Guide.

Author:

Idriss Laouali Abdou

Idriss is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Migrate to Apache Flink 2.2 on Amazon Managed Service for Apache Flink

Post Syndicated from Francisco Morillo original https://aws.amazon.com/blogs/big-data/migrate-to-apache-flink-2-2-on-amazon-managed-service-for-apache-flink/

Migrating to Apache Flink 2.2 on Amazon Managed Service for Apache Flink gives you access to Java 17 runtime, faster checkpoints and recovery through RocksDB 8.10.0, and SQL-native artificial intelligence and machine learning (AI/ML) inference. If you run Flink 1.x today, you might be dealing with an aging Java 11 runtime that will no longer receive standard support by the end of this year, slower state backend performance, and a fragmented API surface split across DataSet, DataStream, and legacy connector interfaces. Flink 2.2 addresses these gaps in a single major version upgrade.

Apache Flink is an open source distributed processing engine for stream and batch data, with first-class support for stateful processing and event-time semantics. Amazon Managed Service for Apache Flink removes the operational overhead of running Flink. You provide your application code, and the service provisions, scales, checkpoints, and patches the infrastructure for you.

In this post, we explain what’s new in Amazon Managed Service for Apache Flink 2.2, provide a guided migration using CLI commands, console instructions, and code examples, and show you how to monitor the upgrade and roll back if needed.

Before you upgrade: Flink 2.2 removes the DataSet API, drops Java 11 support, and replaces legacy connector interfaces. We recommend reviewing the Upgrading to Flink 2.2: Complete Guide and the State Compatibility Guide for Flink 2.2 Upgrades before upgrading production applications.

What’s new in Amazon Managed Service for Apache Flink 2.2

This release spans runtime upgrades, SQL, and Table API capabilities. The following sections break down each area.

Runtime and performance

These changes improve application performance and bring your runtime up to current standards.

  • Java 17 runtime Flink 2.2 requires Java 17. Build your application code with JDK 17 for better garbage collection, a more secure runtime, and modern language features like sealed classes and records. Java 11 is no longer supported.
  • Python 3.12 Flink 2.2 requires Python 3.9+, with Python 3.12 as the default. Python 3.8 is no longer supported.
  • RocksDB 8.10.0 – Your stateful applications benefit from improved I/O performance with the upgraded state backend, resulting in faster checkpoints and recovery.
  • Dedicated collection serializers – Improved serializers for Map, List, and Set types reduce serialization overhead, which lowers checkpoint sizes for applications that use these data structures frequently.
  • Kryo 5.6 – Kryo upgrades from version 2.24–5.6. This has state compatibility implications covered in the migration section.

SQL and Table API highlights

With Flink 2.2, you can:

For details on these features, see the Apache Flink 2.2 release documentation.

Migrating from Flink 1.x to 2.2

In-place version upgrades

You can upgrade a running Flink 1.x application to 2.2 using the UpdateApplication API, the AWS Management Console, AWS CloudFormation, the AWS SDK, and Terraform Modules. The upgrade preserves your application configuration, logs, metrics, tags, and, if your state and binaries are compatible.

Auto-rollback

With auto-rollback turned on, binary incompatibilities detected during job startup trigger an automatic revert to the previous Flink version within minutes, with no manual intervention required. For state incompatibilities that surface as restart loops after a successful upgrade, invoke the Rollback API to return to your previous version and state.

Unsupported open source features

The following Flink 2.2 features aren’t currently supported in Amazon Managed Service for Apache Flink because they’re still considered experimental: Materialized Tables, ForSt State Backend (disaggregated state storage), Java 21, and custom metric reporters/telemetry configurations. We continue to evaluate these features as they mature in the Apache Flink project and will share updates on availability. You can have a closer look to which features are supported in Apache Flink 2.2 features supported

Now that you know what’s changed, the next section walks through the migration process.

Prerequisites

Before starting the migration, confirm that you have the following in place:

  • An existing Apache Flink 1.x application running on Amazon Managed Service for Apache Flink.
  • JDK 17 installed in your local build environment.
  • The AWS Command Line Interface (AWS CLI) installed and configured with permissions to call the kinesisanalyticsv2 APIs (UpdateApplication, CreateApplicationSnapshot, DescribeApplication, RollbackApplication).
  • An Amazon Simple Storage Service (Amazon S3) bucket to upload your updated application JAR.

We recommend testing each phase on a non-production replica of your application before applying the same steps to production.

Step 1: Update your application code

Start by updating your Flink dependencies to version 2.2.0 and replacing deprecated APIs. The following sections show the most common changes.

Update your pom.xml:

<properties>
    <flink.version>2.2.0</flink.version>
    <java.version>17</java.version>
</properties>

Replace legacy Kinesis connectors:

Flink 2.2 removes the FlinkKinesisConsumer and FlinkKinesisProducer classes. The following example shows how to migrate to the FLIP-27 based KinesisStreamsSource.Before (Flink 1.x):

FlinkKinesisConsumer<String> consumer = new FlinkKinesisConsumer<>(
    "my-stream",
    new SimpleStringSchema(),
    consumerConfig);
env.addSource(consumer);

After (Flink 2.2):

KinesisStreamsSource<String> source = KinesisStreamsSource.<String>builder()
    .setStreamArn("arn:aws:kinesis:us-east-1:123456789012:stream/my-stream")
    .setDeserializationSchema(new SimpleStringSchema())
    .build();
env.fromSource(source, WatermarkStrategy.noWatermarks(), "Kinesis Source");

Update connector dependencies:

The following AWS connectors have Flink 2.x-compatible releases:

Connector Flink 2.x Artifact Version
Apache Kafka flink-connector-kafka 4.0.0-2.0
Amazon Kinesis Data Streams flink-connector-aws-kinesis-streams 6.0.0-2.0
Amazon Data Firehose flink-connector-aws-kinesis-firehose 6.0.0-2.0
Amazon DynamoDB flink-connector-dynamodb 6.0.0-2.0
Amazon Simple Queue Service (Amazon SQS) flink-connector-sqs 6.0.0-2.0

During writing, the JDBC, OpenSearch, and Prometheus connectors don’t yet have Flink 2.x-compatible releases. For the latest versions, see the Amazon Managed Service for Apache Flink connector documentation.

Beyond connector updates, make the following code changes:

  • Replace DataSet API usage with the DataStream API or Table API/SQL.
  • Replace Scala API usage with the Java API.
  • Verify that your build targets JDK 17.

Build your updated application JAR and upload it to Amazon S3 with a different file name than your current JAR (for example, my-app-flink-2.2.jar).

Step 2: Check state compatibility

Before upgrading, assess whether your application state is compatible with Flink 2.2. The Kryo upgrade from version 2.24 to 5.6 changes the binary format of serialized state. Applications using POJOs with Java collections (HashMap, ArrayList, HashSet) are the most common source of incompatibility.

Quick compatibility check:

Serialization type Compatible?
Avro (SpecificRecord, GenericRecord) ✅ Yes
Protobuf ✅ Yes
POJOs without collections ✅ Yes
Custom TypeSerializers (no Kryo delegation) ✅ Yes
POJOs with Java collections ❌ No
Scala case classes ❌ No
Types using Kryo fallback ❌ No

Check your logs for Kryo fallback:

Search your application logs for this pattern, which indicates a type is falling back to Kryo serialization:Class class <className> cannot be used as a POJO type

Step 3: Turn on auto-rollback and automatic snapshots

Turn on auto-rollback so the service automatically reverts to the previous version if the upgrade fails. Also, verify that automatic snapshots are turned on. The service takes a snapshot before the upgrade that serves as your rollback point.

Check current settings:

aws kinesisanalyticsv2 describe-application \
    --application-name MyApplication \
    --query 'ApplicationDetail.ApplicationConfigurationDescription.{
        AutoRollback: ApplicationSystemRollbackConfigurationDescription.RollbackEnabled,
        AutoSnapshots: ApplicationSnapshotConfigurationDescription.SnapshotsEnabled
    }'

Turn on both if they’re not already active:

aws kinesisanalyticsv2 update-application \
    --application-name MyApplication \
    --current-application-version-id <version-id> \
    --application-configuration-update '{
        "ApplicationSystemRollbackConfigurationUpdate": {
            "RollbackEnabledUpdate": true
        },
        "ApplicationSnapshotConfigurationUpdate": {
            "SnapshotsEnabledUpdate": true
        }
    }'

Step 4: Take a manual snapshot (recommended)

Although the upgrade process takes an automatic snapshot, taking a manual snapshot gives you a named restore point that you can quickly identify.

aws kinesisanalyticsv2 create-application-snapshot \
    --application-name MyApplication \
    --snapshot-name pre-flink-2.2-upgrade

Verify that the snapshot is ready before proceeding:

aws kinesisanalyticsv2 describe-application-snapshot \
    --application-name MyApplication \
    --snapshot-name pre-flink-2.2-upgrade

Wait until SnapshotStatus is READY.

Step 5: Run the upgrade

Run the upgrade while the application is in RUNNING or READY (stopped) state. The following example upgrades a running application and points to the new JAR.

AWS CLI:

aws kinesisanalyticsv2 update-application \
    --application-name MyApplication \
    --current-application-version-id <version-id> \
    --runtime-environment-update FLINK-2_2 \
    --application-configuration-update '{
        "ApplicationCodeConfigurationUpdate": {
            "CodeContentUpdate": {
                "S3ContentLocationUpdate": {
                    "FileKeyUpdate": "my-app-flink-2.2.jar"
                }
            }
        }
    }'

AWS Management Console:

To upgrade from the console, follow these steps:

  1. Navigate to your application in the Amazon Managed Service for Apache Flink console.
  2. Choose Configure.
  3. Select the Flink 2.2 runtime.
  4. Point to your new application JAR on Amazon S3.
  5. Select the snapshot to restore from (use Latest to start from the most recent snapshot).
  6. Choose Update.

AWS CloudFormation:

Update the RuntimeEnvironment field in your template. AWS CloudFormation now performs an in-place update instead of deleting and recreating the application.

Terraform:

If you manage your Flink application with Terraform, you can perform the same in-place upgrade by updating the runtime_environment and code reference in your aws_kinesisanalyticsv2_application resource. Note: Terraform support for FLINK-2_2 requires AWS provider version 6.40.0 or later (released April 8, 2026). Earlier provider versions don’t recognize this runtime value. First, update your provider version constraint:

terraform {
  required_providers {
    aws = {
      source  = "hashicorp/aws"
      version = ">= 6.40.0"
    }
  }
}

Then run terraform init -upgrade to pull the new provider.Next, update your application resource. Change runtime_environment from “FLINK-1_20” to “FLINK-2_2” and point to your new JAR:

resource "aws_kinesisanalyticsv2_application" "my_app" {
  name                   = "MyApplication"
  runtime_environment    = "FLINK-2_2"
  service_execution_role = aws_iam_role.flink.arn
  application_configuration {
    application_code_configuration {
      code_content_type = "ZIPFILE"
      code_content {
        s3_content_location {
          bucket_arn = aws_s3_bucket.app_code.arn
          file_key   = "my-app-flink-2.2.jar"
        }
      }
    }
    application_snapshot_configuration {
      snapshots_enabled = true
    }
    flink_application_configuration {
      checkpoint_configuration {
        configuration_type = "DEFAULT"
      }
      monitoring_configuration {
        configuration_type = "CUSTOM"
        log_level          = "INFO"
        metrics_level      = "APPLICATION"
      }
      parallelism_configuration {
        auto_scaling_enabled = true
        configuration_type   = "CUSTOM"
        parallelism          = 4
        parallelism_per_kpu  = 1
      }
    }
  }
}

Run the upgrade:

terraform plan    # Review the in-place update
terraform apply   # Apply the runtime change

Terraform will perform an in-place update of the application, changing the runtime version and code location. The application will restart with the new Flink 2.2 runtime. To roll back with Terraform, revert runtime_environment to “FLINK-1_20”, point file_key back to your original JAR, and run terraform apply again. Note that you cannot restore a Flink 2.2 snapshot on Flink 1.x, so the rollback will start from the last Flink 1.x snapshot.

Important Terraform considerations:

  • Auto-rollback and the RollbackApplication API aren’t directly exposed as Terraform resource attributes. If you need auto-rollback during the upgrade, enable it using the AWS CLI (Step 3) before running terraform apply, or use a provisioner/null_resource to call the CLI.
  • Always take a manual snapshot (Step 4) before running terraform apply for the upgrade. Terraform doesn’t automatically snapshot before updating the runtime.

Step 6: Monitor the upgrade

After initiating the upgrade, monitor the application to verify that it completes successfully.

Check application status:

The application should transition through RUNNING → UPDATING → RUNNING. Confirm the runtime version changed to 2.2:

aws kinesisanalyticsv2 describe-application \
    --application-name MyApplication \
    --query 'ApplicationDetail.RuntimeEnvironment'

What to watch for:

Scenario What happens Action
Binary incompatibility Upgrade operation fails. Auto-rollback reverts to the previous version automatically. Check operation logs for the exception, fix your code, and retry.
State incompatibility Upgrade appears to succeed but the application enters restart loops. Monitor numRestarts metric. If restarts are continuous, invoke the Rollback API manually. Review the [State Compatibility Guide].
Successful upgrade numRestarts is zero, uptime is increasing, checkpoints are completing. Proceed to validation.

Key CloudWatch metrics to monitor:

  1. numRestarts: should be zero after upgrade
  2. lastCheckpointDuration: should be similar to pre-upgrade values
  3. numberOfFailedCheckpoints: should remain at zero
  4. uptime: should be steadily increasing

Step 7: Validate application behavior

After the application is running on Flink 2.2:

  • Confirm that data is being read from sources and written to sinks.
  • Compare the output with your pre-upgrade baseline.
  • Monitor latency, throughput, checkpoint duration, and resource utilization.
  • Run for at least 24 hours to confirm stable behavior: no memory leaks, no unexpected restarts, consistent checkpoint sizes.

Step 8: Rollback (if needed)

If the application is running but is unhealthy after the upgrade, invoke the Rollback API:

AWS CLI:

aws kinesisanalyticsv2 rollback-application \
    --application-name MyApplication \
    --current-application-version-id <version-id>

AWS Management Console:

  • Navigate to your application.
  • Choose Actions, Roll back.
  • Confirm the rollback.

During rollback, the application stops, reverts to the previous Flink version and application code, and restarts from the snapshot taken before the upgrade.

Important: You can’t restore a Flink 2.2 snapshot on Flink 1.x. Rollback uses the snapshot taken before the upgrade. This is why Steps 3 and 4 are critical.

Next steps

Your path depends on where you are today:

  1. If you’re new to Apache Flink: Start with the guide to choosing the right API and language, the Amazon Managed Service for Apache Flink getting started guide, and the Amazon Managed Service for Apache Flink workshop.
  2. If you’re running Flink 1.x in production: Follow the migration steps in this post on a non-production replica first, then apply to production. For the complete reference, see the Upgrading to Flink 2.2: Complete Guide and the State Compatibility Guide for Flink 2.2 Upgrades.
  3. If you’re evaluating Flink 2.2 features: Launch a new application on the Flink 2.2 runtime to explore SQL/ML capabilities, the VARIANT data type, and the new join operators. See the Amazon Managed Service for Apache Flink sample applications on GitHub for reference architectures.
  4. If you need help with your migration: Use the Kiro Power and Agent Skill for Amazon Managed Service for Apache Flink to identify compatibility issues in your existing codebase and receive guidance on refactoring steps. You can also open a case through AWS Support, post a question on AWS re:Post for Amazon Managed Service for Apache Flink, or reach out through the Apache Flink community.

For the Apache Flink 2.2 documentation, see nightlies.apache.org/flink/flink-docs-release-2.2. For Amazon Managed Service for Apache Flink documentation, see the Developer Guide. For pricing, see the pricing page.

Conclusion

With Apache Flink 2.2 on Amazon Managed Service for Apache Flink, you get a modern Java 17 runtime, SQL-native AI/ML inference, improved state management performance, and a streamlined API surface. In-place upgrades with state preservation and auto-rollback make the migration straightforward. Test on a replica, follow the steps in this post, and start building on Flink 2.2.


About the authors

Francisco Morillo

Francisco Morillo is a Sr. Streaming Specialist Solutions Architect at AWS, helping customers design and operate real-time data processing applications using Amazon Managed Service for Apache Flink and Amazon Managed Streaming for Apache Kafka.

Mayank Juneja

Mayank Juneja is a Senior Product Manager at AWS, leading Amazon Managed Service for Apache Flink. He lives at the intersection of real-time data streaming and AI, previously driving Flink SQL and AI inference products at Confluent.

Enabling high availability of Amazon EC2 instances on AWS Outposts servers (Part 3)

Post Syndicated from Brianna Rosentrater original https://aws.amazon.com/blogs/compute/enabling-high-availability-of-amazon-ec2-instances-on-aws-outposts-servers-part-3/

This post is part 3 of the three-part series ‘Enabling high availability of Amazon EC2 instances on AWS Outposts servers’. We provide you with code samples and considerations for implementing custom logic to automate Amazon Elastic Compute Cloud (EC2) relaunch on Outposts servers. This post focuses on guidance for using Outposts servers with third party storage for boot and data volumes, whereas part 1 and part 2 focus on automating EC2 relaunch between standalone servers. Outposts servers support integration with Dell PowerStoreHPE Alletra Storage MP B10000 systems, NetApp on-premises enterprise storage arrays, and Pure Storage FlashArray.

Outposts servers provide compute and networking services that are designed for low-latency, local data processing needs for on-premises locations such as retail stores, branch offices, healthcare provider locations, or environments that are space-constrained. Outposts servers use EC2 instance store storage to provide non-durable block-level storage to the instances running stateless workloads. For applications that require persistent storage, you can create a three-tier architecture by connecting your Outposts servers to a third-party storage appliance. In this post, you will learn how to implement custom logic to provide high availability (HA) for your applications running on Outposts servers using two or more servers for N+1 fault tolerance. The code provided is meant to help you get started, and can be modified further for your unique workload needs.

Overview

In the following sections we will show how custom logic can be used to automate EC2 instance relaunch between two or more Outposts servers using boot and data volumes on third party storage. If your EC2 instance fails while using this solution, an Amazon CloudWatch alarm monitoring the EC2 StatusCheckFailed_Instance metric of your source EC2 instance will be triggered, and you will receive an Amazon Simple Notification Service (Amazon SNS) notification. An AWS Lambda function will then relaunch your EC2 instance onto the destination Outposts server that you’ve set up for resiliency. This is done using a launch template created during setup, and the script will connect your relaunched instance to the existing boot and data volumes on your third party storage appliance. This storage device provides shared storage for your Outposts servers. If a single server fails, new instances can connect to existing volumes on the array. This allows for a zero data loss Recovery Point Objective (RPO) and a Recovery Time Objective (RTO) equaling the time it takes to launch your EC2 instance. Take advantage of the features on your storage appliance for configuring data durability and resiliency to hardware failures, and make sure that you are regularly backing up your SAN volumes.

Figure 1 – Solution Architecture for automated EC2 Relaunch

Prerequisites

The following prerequisites are required to complete the walkthrough:

  • Two Outposts servers that can be set up as an active-active or active-passive resilient pair.
  • For workloads with a low threshold for downtime, ensure that your secondary Outpost server that’s used for recovery has a unique service link connection.
  • Outposts servers must be colocated within the same Layer 2 (L2) network.
  • Network latency between the Outposts servers must not exceed 5ms round trip time (RTT).
  • A storage appliance that supports the iSCSI protocol. Credentials to manage the storage appliance initiator/target mappings. See Simplifying the use of third-party block storage with AWS Outposts for more information.
  • If you’re setting this up from an Outposts consumer account, you must configure Amazon CloudWatch cross-account observability between the consumer account and the Outposts owning account to view Outposts metrics in your consumer account.
  • Create launch templates for the EC2 instances that you want to protect, the launch wizard will help you create these.
  • Credentials with permissions for AWS CloudFormation, Amazon EC2, and (optional) AWS Secrets Manager if authentication is required. IAM Permission Examples.md is provided in the repository.
  • A Windows or Linux host that can access the storage appliance and your AWS account (management computer).
  • AWS Outposts iPXE Amazon Machine Image (AMI) from the AWS Marketplace.
  • Python 3.8 or later (recommended) is used to run the init.py script that dynamically creates a CloudFormation stack in the account specified as an input parameter.
  • AWS SDK for Python (Boto3) version 1.26.0 or later recommended.
  • Operating system with iSCSI boot support (Windows Server 2022 and Red Hat Enterprise Linux 9 AMIs are provided).
  • Internet access to AWS service endpoints for the private subnet hosting the recovery Lambda function.
  • Download the repository sample-outposts-third-party-storage-integration.

Walkthrough

The first step is to deploy an EC2 instance configured to boot from a volume on the third-party storage that is prepared with an OS boot image. This step uses the launch wizard portion of the solution.

  1. Download and extract the OutpostServer_Recovery_3Pstorage repository to the management computer that has the AWS SDK for Python (Boto3) and Python installed.
  2. Run launch_wizard from the sample-outposts-third-party-storage-integration directory. You can run interactively or provide arguments for region, subnet, iPXE AMI, storage vendor, storage management ip, and credentials.

Figure 2 – Running launch wizard

  1. When prompted for a feature name, enter sanboot.
  2. For Guest OS type, enter in Linux or Windows.
  3. When prompted “Do you want to continue with this unverified AMI?”, select Y.
  4. The launch wizard will provide a list of instance types available on the Outpost server associated with the subnet you specified. Enter the instance type that you want to use.
  5. The launch wizard will now prompt you for optional EC2 Key Pair, Security Group, and Instance Profile settings for the EC2 instance that you are launching.
  6. Next, the launch wizard prompts you to specify an instance name. Note that specifying an instance name is required to set up automated instance recovery because the instance name is used as part of the recovery process.

Figure 3 – Taking user input for variable values

  1. The launch wizard prompts for root volume size. This is the root volume that the iPXE AMI boots from. The default is a 1GB volume on the Outpost server instance storage.
  2. Next, the launch wizard prompts you to select which third party storage controller you want to use based on the management ip that you specified. In this example, we are using NetApp, so I select a NetApp Storage Virtual Machine (SVM) named outpost_iscsi.
  3. If the connection to the storage array is successful and the protocol is available (iSCSI or NVMe over TCP) you are provided additional storage options for initiator group and logical unit number (LUN).
  4. In this example, we are using NetApp with iSCSI, so I can select an existing initiator group or create a new one.
  5. You can specify an existing initiator qualified name (IQN), or the launch wizard can generate a new one. IMPORTANT: Make sure that IQNs are unique to each instance because duplicates can cause data corruption.
  6. Next the launch wizard prompts which LUN’s you want to connect to this instance. For this example, I am going to use a Windows Server 2022 boot volume that I already created on the NetApp storage array.
  7. You are now asked which storage array target interface you want to use for connecting to these LUNs.
  8. The launch wizard provides the capability to specify guest OS scripts to customize the OS after sanboot. Combining this capability with storage array cloning provides a streamlined process for deploying new instances.
  9. The launch wizard now displays the EC2 user data template that it generated for use with the iPXE AMI and asks if you want to proceed with launching the instance.
  10. After the EC2 instance is launched, select yes to proceed with automated instance recovery setup.

Figure 4 – Running launch template creation script

Generating EC2 launch templates for recovery and failback

In the second step, we are generating EC2 launch templates for the EC2 instance launched in step 1. Launch templates can be generated for the primary and secondary Outpost servers. The launch template for the secondary Outpost server can be used for automated or manual recovery of the EC2 instance. Failback to the primary Outpost server is manual using the primary launch template.

  1. Select the instance that you want automated recovery for and select the subnet that you launched the instance in. This subnet represents the primary Outpost server that the instance is running on.

Figure 5 – Selecting subnets for EC2 instance relaunch

  1. When prompted to create a second launch template for Outpost server recovery, select yes, and then select to use the same instance (for recovery on different Outpost server).
  2. When you get a list of available subnets, select the subnet that’s associated with your secondary Outpost server. This is the server that the EC2 instance will be launched on in the event of the EC2 StatusCheckFailed_Instance metric triggers the CloudWatch alarm.
  3. You will see both launch templates created successfully.

Deploying automated EC2 instance recovery

The third step creates a CloudFormation template for monitoring, notifications, and automated recovery of the EC2 instance deployed in step 1. The CloudFormation template automatically captures the instance and secondary launch template information necessary for automatic recovery.

  1. Select Y to set up automated recovery. This will create a CloudFormation stack.
  2. Provide a name and description for the CloudFormation stack.
  3. Select whether you want automated recovery or notification only. This provides flexibility to choose manual or automatic recovery based on whether you want to verify the primary Outpost server is down before initiating recovery.
  4. In the AWS CloudFormation console, monitor the CloudFormation stack creation process.

Figure 6 – CloudFormation stack creation in progress

  1. After the CloudFormation Stack is complete, you have successfully deployed an EC2 instance using third party storage for boot and data volumes on a primary Outpost server. You also created instance recovery capabilities by using the Amazon Outpost server automated recovery solution for third party storage.
  2. You can verify whether the EC2 StatusCheckFailed_Instance is healthy under the Alarms section in the Amazon CloudWatch console.

Considerations

The logic discussed in this post relies on the secondary destination Outposts server having a connected service link. For more information about how to create a highly available service link connection for your Outpost servers, see the Networking section of AWS Outposts High Availability Design and Architecture Considerations whitepaper.

Clean up

Confirm whether it is safe to terminate the Amazon EC2 instance that you launched with this walkthrough. The operating system and data volumes are on the third party storage, so EC2 instance termination only removes the iPXE AMI from the Outposts server instance storage. To clean up, complete the following steps.

  1. Terminate the Amazon EC2 instance. Then, verify that the Instance state is Terminated to ensure that the instance is not using Outposts server resources.
  2. Delete the Amazon EC2 Launch Templates associated with the Amazon EC2 instance that you terminated. The names of the launch templates that were automatically generated will start with ‘lt-‘, followed by the instance name and the instance id. If you generated a recovery launch template, it will have a ‘-recovery’ suffix in the name.
  3. Delete the AWS CloudFormation Stack. The Stack name will start with ‘autorestart-‘ followed by the Amazon EC2 instance name.
  4. Clean up your initiators, initiator group, and LUNs on the third party storage array.

Conclusion

With the use of custom logic through AWS tools such as CloudFormation, CloudWatch, Amazon SNS, and AWS Lambda, you can architect for HA for stateful workloads on Outposts server. By implementing the custom logic in this post, you can automatically relaunch EC2 instances running on a source Outposts server to a secondary destination Outposts server if an instance fails, and connect to existing volumes on a shared storage appliance for recovery. This also reduces the downtime of your applications in the event of a hardware or service link failure. The code provided in this post can be further expanded upon to meet the unique needs of your workload.

While the use of infrastructure-as-code (IaC) can improve your application’s availability and be used to standardize deployments across multiple Outposts servers, it’s crucial to do regular failure drills to test the custom logic in place. This is to make sure that you understand your application’s expected behavior on relaunch in the event of a failure. To learn more about Outposts servers, visit the Outposts servers User Guide. Reach out to your AWS account team, or fill out this form to learn more about Outposts servers.

Standardizing construct properties with AWS CDK Property Injection

Post Syndicated from Marco Frattallone original https://aws.amazon.com/blogs/devops/standardizing-construct-properties-with-aws-cdk-property-injection/

Standardizing CDK construct properties across a large organization requires repetitive manual effort that scales poorly as teams and repositories grow. Development teams working with AWS Cloud Development Kit (AWS CDK) must apply the same configuration properties across similar resources to meet security, compliance, and operational standards but manual configuration leads to drift, maintenance burden, and compliance gaps. In this post, you learn how to use Property Injection, a feature introduced in AWS CDK v2.196.0, to automatically apply default properties to constructs without modifying existing code.

The Challenge of Infrastructure Standardization

Organizations implementing infrastructure as code face a fundamental tension between developer productivity and operational consistency. CDK provides abstractions for defining cloud resources, but ensuring compliance with organizational security policies, compliance requirements, and operational standards requires repetitive manual configuration.
Consider this scenario: an organization’s security policy requires that all SecurityGroups disable outbound traffic by default. Development teams must apply these settings to every SecurityGroup:


new SecurityGroup(stack, 'api-sg', {
  vpc: myVpc,
  allowAllOutbound: false,        // Required by security policy
  allowAllIpv6Outbound: false     // Required by security policy
});

new SecurityGroup(stack, 'db-sg', {
  vpc: myVpc,
  allowAllOutbound: false,        // Same configuration repeated
  allowAllIpv6Outbound: false     // Same configuration repeated
});

This manual approach creates four specific problems:

  • Configuration drift: Teams omit required properties or apply them inconsistently
  • Maintenance burden: Policy updates require coordinated changes across multiple repositories and teams
  • Developer friction: Repetitive configuration tasks slow development velocity and increase cognitive load
  • Compliance gaps: Manual processes introduce human error, creating security or compliance violations

Custom construct libraries address these challenges but require refactoring every construct instantiation in existing code and create learning curves for development teams already familiar with standard CDK patterns.

Introducing Property Injection

AWS CDK Property Injection addresses these challenges by automatically applying default properties to constructs without requiring changes to existing code.

Property Injection is a feature introduced in AWS CDK v2.196.0 that intercepts construct creation and automatically applies organizational defaults. With this approach, you can enforce standards consistently while preserving existing development workflows and code patterns.

After implementing Property Injection, the same SecurityGroup creation requires only the vpc parameter, security defaults are applied automatically:

// Your existing code remains unchanged
new SecurityGroup(stack, 'my-sg', {
  vpc: myVpc
  // Security defaults applied automatically by Property Injection
});

The key benefits of this approach include:

  • Zero-impact adoption: Existing CDK code continues to work without modification
  • Centralized policy management: Standards are defined once and applied automatically
  • Consistent enforcement: Policies are applied uniformly across all applications and teams
  • Reduced maintenance overhead: Policy updates require changes in only one location
This diagram shows the five-step Property Injection process in a clear two-column format. The left column outlines each process step, while the right column shows the corresponding implementation details with properly formatted TypeScript code. The flow demonstrates how CDK intercepts SecurityGroup creation, applies organizational security defaults through property injectors, merges them with developer-specified properties, and creates a fully configured SecurityGroup that meets both developer requirements and organizational standards.

Figure 1: CDK Property Injection Mechanism

Property Injection operates transparently within CDK, intercepting construct creation to apply predefined defaults before merging them with any properties explicitly provided by developers. This ensures that organizational standards are consistently applied while maintaining the flexibility for developers to override defaults when specific use cases require it.

Understanding the Implementation Approach

Property Injection works by implementing the IPropertyInjector interface, which allows you to define default properties for specific construct types. These injectors are registered with CDK stacks and automatically apply their defaults during construct instantiation.
The implementation follows three steps: define the defaults you want to apply, register the injector with your stack, and let CDK handle the automatic application of these defaults to matching constructs.

Implementation Guide

This section shows you how to implement Property Injection for SecurityGroup constructs.

Step 1: Create a Property Injector

Create a class that implements the IPropertyInjector interface:

import { IPropertyInjector, InjectionContext } from 'aws-cdk-lib';
import { SecurityGroup, SecurityGroupProps } from 'aws-cdk-lib/aws-ec2';

export class SecurityGroupDefaults implements IPropertyInjector {
  readonly constructUniqueId: string;

  constructor() {
    this.constructUniqueId = SecurityGroup.PROPERTY_INJECTION_ID;
  }

  inject(originalProps: SecurityGroupProps, context: InjectionContext): SecurityGroupProps {
    return {
      // Apply organizational defaults
      allowAllIpv6Outbound: false,
      allowAllOutbound: false,
      // Original properties override defaults when specified
      ...originalProps,
    };
  }
}

Step 2: Add the Injector to Your Stack

Apply the injector to your CDK stack:

import { Stack } from 'aws-cdk-lib';
import { SecurityGroupDefaults } from './security-defaults';

const stack = new Stack(app, 'MyStack', {
  propertyInjectors: [
    new SecurityGroupDefaults()
  ]
});

Step 3: Use Constructs Normally

Create constructs as usual. The injector applies defaults automatically:

// This SecurityGroup receives the injected defaults:
// - allowAllOutbound: false
// - allowAllIpv6Outbound: false
new SecurityGroup(stack, 'my-sg', {
  vpc: myVpc
});

// You can override defaults when necessary
new SecurityGroup(stack, 'special-sg', {
  vpc: myVpc,
  allowAllOutbound: true  // Overrides the injected default
});
This side-by-side comparison shows the difference between manual configuration and Property Injection. The left side (Before) shows three SecurityGroup definitions, each requiring manual specification of allowAllOutbound: false and allowAllIpv6Outbound: false, leading to repetitive code, inconsistency risk, and maintenance burden. The right side (After) shows the same SecurityGroups created with the VPC parameter alone after a one-time Property Injection setup, demonstrating the DRY principle, consistent defaults, and reduced maintenance.

Figure 2: CDK Code Before vs After Property Injection

Property Injection vs L2 Constructs

You can achieve the same enforcement of default properties by creating custom L2 constructs with built-in defaults. However, Property Injection is better suited for standardizing existing codebases without refactoring, while L2 Constructs are better suited for new projects where you want custom APIs and multi-resource abstractions.

This decision tree guides the selection between Property Injection and L2 Constructs for CDK standardization. Starting with existing CDK applications, it evaluates willingness to accept potential breaking changes from new defaults. If breaking changes are acceptable or no existing code exists, it assesses whether custom APIs, naming improvements, or multi-resource patterns are needed beyond simple defaults. The tree leads to three outcomes: Property Injection (blue) for transparent defaults with existing code compatibility, L2 Constructs (orange) for custom APIs and purpose-built abstractions, or a Hybrid approach (green) combining both techniques for maximum flexibility.

Figure 3: Decision Tree – Property Injection vs L2 Constructs

Implementation Comparison

Consider an application with multiple SecurityGroup instantiations that need standardized security defaults.

L2 Construct approach requires creating a custom construct and updating each instantiation:

// Step 1: Create custom L2 construct
export class SecureSecurityGroup extends SecurityGroup {
  constructor(scope: Construct, id: string, props: SecurityGroupProps) {
    super(scope, id, {
      allowAllOutbound: false,
      allowAllIpv6Outbound: false,
      ...props
    });
  }
}

// Step 2: Update each instantiation throughout your codebase
// Change from:
new SecurityGroup(stack, 'sg1', { vpc: myVpc })
new SecurityGroup(stack, 'sg2', { vpc: myVpc })
new SecurityGroup(stack, 'sg3', { vpc: myVpc })

// To:
new SecureSecurityGroup(stack, 'sg1', { vpc: myVpc })
new SecureSecurityGroup(stack, 'sg2', { vpc: myVpc })
new SecureSecurityGroup(stack, 'sg3', { vpc: myVpc })

Property Injection approach requires one-time stack configuration:

// Step 1: Add injector to stack configuration
stack.propertyInjectors = [new SecurityGroupDefaults()];

// Step 2: Existing SecurityGroup calls receive defaults automatically
new SecurityGroup(stack, 'sg1', { vpc: myVpc })  // Gets defaults
new SecurityGroup(stack, 'sg2', { vpc: myVpc })  // Gets defaults  
new SecurityGroup(stack, 'sg3', { vpc: myVpc })  // Gets defaults

Key Differences

Property Injection works with existing construct calls, requiring no changes to how developers instantiate SecurityGroups or other constructs. This approach overrides constructs from external libraries and can be implemented without modifying existing code. Developers continue using familiar CDK APIs without learning new interfaces.

L2 Constructs require updating all constructor calls throughout your codebase. This approach cannot modify third-party construct creation since you must change each instantiation to use your custom construct. Implementation requires refactoring existing code and developers must learn your custom construct APIs instead of standard CDK interfaces. L2 constructs serve multiple purposes beyond complex business logic – simple L2 constructs provide domain-specific naming conventions and cleaner APIs, while complex L2 constructs orchestrate three or more resources and implement business rules.

When to Choose Each Approach

Choose Property Injection when you need to standardize existing infrastructure. Property Injection excels in scenarios where you already have CDK applications deployed and need to apply consistent defaults retroactively. Property Injection works transparently with existing code, requiring no changes to how developers instantiate constructs. This makes it useful when you have existing CDK applications that you want to standardize without disrupting current development workflows.

Property Injection also solves the challenge of applying defaults to constructs from third-party libraries. Since you cannot modify external library code, Property Injection enforces organizational standards on any construct type, regardless of its source. Additionally, when you want to implement standards without changing existing code, Property Injection operates at the framework level, automatically applying defaults during construct instantiation without requiring developers to modify their existing implementations.

Choose L2 Constructs when you need custom APIs or multi-resource patterns. L2 Constructs provide the right abstraction when you want to create purpose-built interfaces that differ from standard CDK APIs. This includes simple wrappers with domain-specific naming, complex business logic, validation rules, or multi-resource orchestration patterns. L2 Constructs excel when you want to create opinionated APIs that simplify common patterns by hiding complexity behind intuitive interfaces.

L2 Constructs suit new application development where you can design the API from the start. This approach creates purpose-built abstractions that match your organization’s specific use cases and terminology. Unlike Property Injection, which applies defaults to existing construct APIs, with L2 Constructs you can design entirely new APIs that directly represent your business domain and operational patterns.

Implementation Patterns

Stack Integration Methods

The CDK provides two methods for adding Property Injectors to stacks:

This diagram demonstrates two methods for adding Property Injectors to CDK stacks. Method 1 (blue) shows adding injectors directly in the Stack constructor’s propertyInjectors array. Method 2 (orange) shows using PropertyInjectors.of(stack).add() after stack creation. Both methods produce identical results with green checkmarks indicating success. The diagram includes usage examples showing normal SecurityGroup instantiation (blue) that inherits defaults automatically, and override scenarios (orange) where developers explicitly override injected defaults. The bottom section shows the resulting CloudFormation output: default SecurityGroups have empty egress rules (green), while overridden ones include outbound traffic rules (orange).

Figure 4: CDK Stack Integration Methods

Method 1: Stack Constructor

const stack = new Stack(app, 'MyStack', {
  propertyInjectors: [new SecurityGroupDefaults()]
});

Method 2: PropertyInjectors.of()

const stack = new Stack(app, 'MyStack');
PropertyInjectors.of(stack).add(new SecurityGroupDefaults());

Both methods produce the same result. Choose the method that best fits your existing code structure. For more details, see the PropertyInjectors API documentation.

Organization-Wide Implementation

For organization-wide standardization, create a shared library of injectors:

// @myorg/cdk-injectors package
export const ORGANIZATION_INJECTORS: IPropertyInjector[] = [
  new SecurityGroupDefaults(),
  new LambdaFunctionDefaults(),
  new S3BucketDefaults(),
];

// Teams import and use the shared injectors
import { ORGANIZATION_INJECTORS } from '@myorg/cdk-injectors';

const stack = new Stack(app, 'TeamStack', {
  propertyInjectors: ORGANIZATION_INJECTORS
});

Scope Hierarchy

Property Injectors can be applied at different levels in the CDK construct tree:

This diagram illustrates the three-level hierarchy of Property Injector scopes in CDK with integrated resolution examples. The App level (blue) shows a BucketInjector ‘b1’ that applies globally, with an example showing how Stack2 buckets use this injector. The Stage level (green) demonstrates a FunctionInjector ‘f1’ that applies to all stacks within the stage, including an example of Stack1 functions using this injector. The Stack level (orange) shows two stacks: Stack1 with its own BucketInjector ‘b2’ that overrides the app-level injector, and Stack2 with no injectors that inherits from parent scopes. The Resolution Rules box (green) explains that CDK searches from most specific (stack) to most general (app), with the first match winning per construct type. Arrows show the hierarchical relationship between scopes.

    Figure 5: CDK Scope Hierarchy & Injector Resolution
  • App level: Applies to all stacks in the application
  • Stage level: Applies to all stacks within a specific stage
  • Stack level: Applies only to constructs within a specific stack

CDK searches for applicable injectors starting from the construct’s immediate parent scope and moving upward. The first matching injector for each construct type is used.

Best Practices

When implementing Property Injection, begin with high-impact constructs like SecurityGroups, VPCs, and Lambda functions that require repetitive configuration.

These constructs have the highest frequency of misconfiguration and the most direct compliance impact, making them the most valuable targets for early adoption.

Document your defaults by explaining what properties your injectors provide and why. Include examples and link to relevant policies that drive the requirements. With this documentation, developers can understand standards and make informed override decisions.

Write automated tests using CDK testing utilities to verify that injectors apply expected defaults. Test both standard scenarios and cases where developers override properties to prevent regressions when updating injector logic.

Version injectors carefully using semantic versioning principles because changes affect all applications. Coordinate updates across teams and provide migration guides for breaking changes or changes to default values.

Design override mechanisms so that developers can handle edge cases while benefiting from organizational standards. Property Injection operates as defaults, not restrictions, so design injectors to merge gracefully with developer-specified properties.

Limitations and Considerations

Property Injection operates as a default mechanism rather than a compliance enforcement system. Developers retain the ability to override injected properties, which means organizations cannot rely solely on Property Injection for strict compliance requirements. For teams that need mandatory compliance, combine Property Injection with CDK Aspects or AWS Config rules to validate and enforce standards.

The feature works exclusively with L2 constructs, as documented in the official AWS CDK guidance. The IPropertyInjector interface targets specific L2 construct types, and L1 (CloudFormation) constructs use different instantiation patterns that bypass the property injection mechanism entirely. Organizations with L1 construct usage need alternative standardization approaches.

Property Injection introduces debugging complexity because injected properties do not appear directly in application code. Developers troubleshooting construct behavior must understand which injectors apply to specific construct types and how those injectors modify properties. This hidden behavior requires documentation that lists each injector, the properties it sets, and the policy it enforces, along with clear naming conventions to maintain code clarity.

The feature requires CDK v2.196.0 or later, which affects adoption timelines for organizations using older CDK versions. Teams must plan upgrade paths and test compatibility before implementing Property Injection across their applications.

Conclusion

Property Injection provides a mechanism for applying consistent default properties to CDK constructs without requiring changes to existing code. This approach reduces repetitive configuration, improves consistency, and simplifies maintenance of CDK applications.
Property Injection is the right choice for organizations that need to standardize construct configurations across existing codebases while preserving developer workflows. When combined with proper testing and documentation, Property Injection becomes a reliable foundation for infrastructure governance across your organization.

About the authors:

Put Cheung

Put Cheung is a Senior Software Development Engineer at AWS Security. He is a part of a team that is making it easier for builders to configure AWS Resources securely. AWS CDK Property Injection is an important step toward this goal.

Rico Huijbers

Rico Huijbers is a Software Engineer at Amazon Web Services. He is extremely lazy and is therefore on a quest to eradicate the need for repetitive manual work from software engineering. Rico loves working on AWS CDK—it’s the tool he wishes he had 5 years earlier.

Marco Frattallone

Marco Frattallone is a Senior Technical Account Manager at AWS focused on supporting Partners. He works closely with Partners to help them build, deploy, and optimize their solutions on AWS, providing guidance and leveraging best practices. Marco focuses on helping Partners adopt emerging AWS services and translate technical capabilities into business outcomes. Outside work, he enjoys outdoor cycling, sailing, and exploring new cultures.

6,000 AWS accounts, three people, one platform: Lessons learned

Post Syndicated from Ben Freiberg original https://aws.amazon.com/blogs/architecture/6000-aws-accounts-three-people-one-platform-lessons-learned/

This post is cowritten by Julius Blank from ProGlove.

As software-as-a-service (SaaS) platforms grow, balancing speed of innovation with strong security and tenant data isolation becomes critical. While the same AWS Identity and Access Management (IAM) mechanisms secure both shared and dedicated environments, establishing a hard security boundary is often easier in an account-per-tenant model because the account itself becomes the isolation boundary. In shared-account deployments, you instead rely on resource-level boundaries such as tenant-scoped IAM policies and data partitioning. This multi-tenancy increases architectural and operational complexity and can introduce security challenges if safeguard mechanisms are not properly designed and enforced. By adopting an account-per-tenant model on Amazon Web Services (AWS), you can achieve clearer security boundaries, streamlined ownership of services, and more transparent cost attribution, but this comes at the expense of increased investment in platform automation.

At ProGlove, we build smart wearable barcode scanning solutions that connect frontline workers to digital workflows. Our scanners integrate with Insight, our AWS based SaaS platform, to provide real-time process visibility. This helps customers in manufacturing, logistics, and retail improve their productivity, reduce errors, and enhance ergonomics on the shop floor.

This post describes why we chose a account-per-tenant approach for our serverless SaaS architecture and how it changes the operational model. It covers the challenges you need to anticipate around automation, observability and cost. We will also discuss how the approach can affect other operational models in different environments like an enterprise context.

Why multi-account?

Many SaaS providers begin their journey with a straightforward, dedicated deployment model, often with one AWS account per tenant. This approach makes initial implementation straightforward and limits the scope of issues, but as the platform scales, operational overhead and inefficiencies from idle or underutilized resources increase. These inefficiencies can be mitigated with serverless architectures that scale automatically to demand. Over time, providers often look to shared or multi-tenant models to consolidate operations and improve cost efficiency. However, this shift introduces new challenges as the number of tenants and services grows:

  • Blast radius – An accidental misconfiguration or vulnerability could expose multiple tenants.
  • Quota limits – Tenants in a single AWS account share the same quotas.
  • Operational complexity – Shared infrastructure makes it difficult to reason about ownership of resources.
  • Customization limits – Making changes for one tenant risks impacting others.
  • Cost visibility – Attributing resource usage to individual tenants is challenging.

Choosing between a dedicated or shared model is ultimately a trade-off. Dedicated deployments are more straightforward to build but require investment in SaaS operations and orchestration to manage at scale, whereas shared models reduce operational overhead but increase architectural and management complexity.

AWS recommends a multi-account strategy to organizing your AWS environment. At scale, the AWS account boundary is the easiest way to implement isolation. Accounts are fully isolated containers for compute, storage, networking and more, with no shared scope unless you explicitly configure it.

Working backwards from our use case, we decided to take this model to its logical extreme: every tenant gets their own AWS account. The services they consume are deployed directly into that account. In that account, we deploy the full set of microservices that the tenant requires. These services run exclusively with that tenant’s data and configuration. At our current scale, ProGlove manages approximately:

That translates to over 120,000 deployed service instances and roughly 1,000,000 Lambda functions in production. The following diagram shows an overview of the main services used in our platform.

AWS multi-account architecture diagram showing hierarchical organization with Root, Audit, Monitoring, Deployment, and Tenant accounts containing various AWS services

Benefits of the account-per-tenant model

This model brings several benefits that directly support security, agility, and operational clarity, including a strong isolation model, simplified mental model, customization per tenant, and transparent cost attribution. Tenant data is not co-located. Each account has its own storage, compute, and permissions. If a security issue, runaway process, or misconfiguration occurs, the impact is limited to that tenant’s account while other tenants remain unaffected. For developers, they don’t need to think multi-tenancy as a deployed service instance always belongs to exactly one tenant. This reduces cognitive load and simplifies debugging. Developers can easily be provided with isolated, production-like tenant accounts to eliminate the gap between development and production environments. You can modify, test, and migrate individual accounts independently. This helps to create tailored deployments, such as activating premium features for certain tenants, without impacting the overall system.

AWS Cost Explorer and linked accounts make it straightforward to report and charge back costs on a per-tenant basis. For SaaS providers with consumption-based pricing models, this becomes a strong advantage.

When conducting an AWS Well-Architected Framework review together with AWS, we found that many items from the operational excellence as well as the security pillar didn’t even apply to our setup anymore. This made completing those review sections quick and straightforward.

Challenges and trade-offs

The account-per-tenant model, like most architectural choices, involves trade-offs. Although the model provides strong isolation, it introduces challenges in platform operations. The approach shifts complexity away from application development to platform development.

Provisioning, configuring, and managing thousands of accounts isn’t feasible manually. Automation of account creation, baseline setup, IAM roles, guardrails, and service enablement is mandatory. We rely on AWS Organizations, its service control policies (SCPs), and AWS CloudFormation StackSets, as well as custom tooling to handle this.

Some of the involved workflows lend themselves well to automation, whereas others can be implemented more effectively using traditional scripting and manual operations, as long as the overhead introduced is low enough. For example, account creation is a fully automated process using AWS Step Functions, but the retirement and closure of accounts are performed manually through regularly run scripts.

AWS account lifecycle management diagram showing automated provisioning with Step Functions and CloudFormation, plus manual retirement process with scripts

Some AWS services are billed per provisioned resource and independent of utilization as opposed to fully scaling to zero when not used. Prominent examples are Amazon Elastic Compute Cloud (Amazon EC2) or Amazon Relational Database Service (Amazon RDS), where resources need to be provisioned to use the service. Even the smallest EC2 instance type is charged at around USD $3, which adds up to USD $3,000 when deployed into 1,000 accounts. By contrast, serverless offerings such as AWS Lambda or Amazon DynamoDB automatically scale based on actual usage, minimizing idle resource costs. Although the per‑invocation or per‑request pricing for serverless services can seem higher, these models often offset the operational overhead and resource wastage associated with always‑on infrastructure. In any case, costs should be carefully modeled, measured, and optimized.

Monitoring infrastructure across accounts and Regions at scale is significantly harder than monitoring a handful of accounts. Observability tooling should be centralized, but without reintroducing the very risks that accounts are meant to isolate. It’s important to point out that Amazon CloudWatch offers greatly improved cross-account observability features today than when we started, for example, the Observability Access Manager.

Developers, operations teams, and platform services and tools need to operate across accounts on a daily basis. This requires a robust identity model with IAM roles and cross-account trust policies. If not designed carefully, this can become a source of complexity and security risk. Also, make sure to follow the best practice of avoiding long-lived credentials because these introduce a major security threat and monitoring effort if deployed into many accounts. AWS service limits are enforced per account. In a shared-account model, you monitor a single set of quotas. In an account-per-tenant setup, quota management becomes distributed and harder to predict. Proactive quota requests and monitoring are essential. For example, AWS Lambda employs a quota for the number of concurrent executions that functions in a single account share. In case a tenant is under heavier load, it’s likely for the corresponding account to experience throttling errors of Lambda functions, which is why it’s essential to provide a single pane of glass view to keep track of the quota usage and adapt as necessary. Although multi-account strategies are common at the enterprise level, adopting them at the SaaS tenant level is less common. Patterns, tooling, and reference architectures are still evolving, which means building custom solutions becomes necessary. Make sure to research available resources and consult AWS so you don’t reinvent the wheel.

Scaling observability across tenants

Observability can become a challenge in this architecture. If each tenant account emits its own logs, metrics, and traces, operational visibility becomes fragmented. For enhanced cross-account capabilities, we used a third-party observability solution. As an example, we forward telemetry (logs and metrics) to a central application where we can configure multi-alerts that are defined one time and applied to tenant accounts individually. This not only reduces cost but also simplifies the operational experience. Engineers interact with a single view, while underlying telemetry still originates from isolated accounts.

It’s vital to use tags whenever possible to correlate telemetry data as well as to use a consistent tagging and naming convention. Depending on the scale of operations, consider using AWS Organizations tag policies to enforce a consistent scheme. As an example, we include fields for the source AWS account ID in most metrics and logs to make sure we can easily drill down into the data for one particular tenant.

Key takeaways:

  • Don’t replicate per-account alarms blindly. Use streaming and aggregation.
  • Use tags for consistent context across thousands of instances.
  • Stay current with AWS feature releases with the AWS News Blog: metric streams, Amazon EventBridge integrations, Amazon CloudWatch Observability Access Manager, and other offerings can streamline your observability stack.
  • Follow the What’s New with AWS feed.

CI/CD and deployment at scale

Deploying microservices into one AWS account is straightforward. Deploying the same service into thousands of accounts requires a different approach. Our application code is stored in a monorepo, which helps us to enforce the same version of libraries or Lambda layers among others. The following diagram illustrates how we update many tenant accounts using AWS CodePipeline combined with AWS CloudFormation StackSets to deploy the applications. Each pipeline execution updates many target accounts in parallel, with only a single StackSet update operation in a central account.

AWS CloudFormation StackSet architecture showing centralized deployment from Infrastructure Account to multiple Tenant Accounts via CodePipeline

While this provides the necessary scale, it also introduces new failure modes:

  • Partial rollouts – If one account fails to deploy, rollback or retry strategies need to be defined and tested.
  • Pipeline duration – Large-scale updates can take significant time to propagate.
  • Tooling maturity – StackSets are powerful but still evolving, and operational edge cases are possible.

In practice, this requires investing in platform engineering. A dedicated team builds and maintains internal tools that abstract deployment complexity away from service developers. Developers remain focused on business logic, and the platform team takes care of consistency and reliability across accounts.

Cost management

Cost modeling changes significantly with this architecture. In a shared account, many costs are pooled, making per-tenant attribution difficult. In a account-per-tenant model, costs are naturally segmented by account .On the positive side, tenant-specific cost reporting is trivial. SaaS providers can align billing directly with AWS usage and even get monthly reporting per tenant automatically through AWS billing.

Costs that scale per account needs to be carefully considered. At scale, even small charges per resource become meaningful. For example, collecting metrics from thousands of accounts requires careful planning and the chosen approach has great influence on costs. At this scale, it isn’t feasible to use standard observability tooling out of the box because the volume of collected data can make per‑account costs economically unsustainable. Instead, focus on understanding which metrics you need to monitor and select an observability approach that allows you to implement that. As a recommendation, evaluate cost multipliers early. Services that scale linearly with the number of accounts should be avoided where possible. Make sure to verify your assumptions with actual measurements.

Operational considerations

To succeed with this model, you need to be prepared to invest in platform capabilities:

  • Account management – Automate everything from creation to decommissioning.
  • Baseline guardrails – Enforce compliance and security controls using SCPs and a strict IAM management.
  • Developer training – Make sure teams understand the scope and boundaries of their services.
  • CI/CD investment – Pipelines need to scale to thousands of accounts without blocking innovation.
  • Observability discipline – Monitoring needs to be consistent, centralized, and cost-effective.

Conclusion

In this post, we described how ProGlove implemented a large-scale account-per-tenant model on AWS and how that model shifts complexity from service code to platform operations. This is a trade-off that requires more platform automation, scalable CI/CD pipelines, and disciplined observability practices. The benefits are strong tenant and workload isolation, transparent costs, and severely reduced blast radius. These benefits are key for platform providers operating at scale with a strictly limited operations team size. Managing thousands of AWS accounts with three people might sound impossible. But with the right architectural choices, every new workload adds only marginal operational load while the platform absorbs the exponential scale. The team size stays constant, and efficiency grows with every account added. If security, compliance, and clarity are top priorities, this approach can serve as a strong foundation for your platform. Working backwards from these requirements can help you achieve the same balance: scaling your tenant base drastically, without scaling your operations team at the same rate.

Read more on Best practices for a multi-account environment, Managing stacks across accounts and Regions with StackSets, and the SaaS Lens for the AWS Well-Architected Framework.


About the authors

Mastering millisecond latency and millions of events: The event-driven architecture behind the Amazon Key Suite

Post Syndicated from Ali Ufuk Yucel original https://aws.amazon.com/blogs/architecture/mastering-millisecond-latency-and-millions-of-events-the-event-driven-architecture-behind-the-amazon-key-suite/

Background

Amazon Key empowers customers to securely manage access to their homes and businesses through innovative solutions. Through a suite of consumer and business products, the Amazon Key team is transforming how customers receive deliveries and manage access to their spaces. Our In-Garage Delivery service offers a secure and convenient solution for receiving Amazon packages and groceries directly inside customers’ garages. For property managers and building owners, Amazon Key provides comprehensive access management solutions that enable safe and efficient delivery operations in apartment buildings and gated communities, enhancing both security and convenience for residents.

In this post, we explore how the Amazon Key team used Amazon EventBridge to modernize their architecture, transforming a tightly coupled monolithic system into a resilient, event-driven solution. We explore the technical challenges we faced, our implementation approach, and the architectural patterns that helped us achieve improved reliability and scalability. The post covers our solutions for managing event schemas at scale, handling multiple service integrations efficiently, and building an extensible architecture that accommodates future growth.

Opportunities

Service Coupling and System Fragility

Our legacy architecture faced significant challenges stemming from its tightly coupled design, where service interactions created a complex web of dependencies impacting system stability and scalability. Making service modifications was particularly challenging, as adding or removing services required careful consideration of numerous interdependencies. An incident highlighted this vulnerability when an issue in Service-A triggered a cascade of failures across many upstream services, with increased timeouts leading to retry attempts and ultimately resulting in service deadlocks. System fragility was further demonstrated when problems with a single device vendor, despite being responsible only for specific delivery operations, caused widespread degradation across multiple system services.

Loose Event Schemas

Our old event management infrastructure lacked explicit schema definitions and employed a loosely-typed data architecture, leading to several critical issues. Events were difficult to maintain as use cases expanded, and the absence of formal schema documentation impacted transparency and team collaboration. The design made it almost impossible to implement backward-incompatible changes, such as removing unused fields or events for performance optimization. Without a repository for schema management, team-to-team collaboration for schema modifications (adding fields, removing fields, deprecating fields, or marking fields as required) became challenging. The system also lacked organized validation logic, making it difficult for publishers to identify invalid events before they entered the system. Additionally, the loosely typed schemas lost important semantic context, such as inheritance and composition relationships between different event schemas.

Inconsistent Event Routing and Management

The event routing logic was manually managed and lacked the sophistication needed for growing use cases. The system only supported basic validation of events, primarily checking for required fields, with limited capability for extending validation rules or implementing more complex routing logic. Features that were commonly available in off-the-shelf solutions, such as parallel publishing to multiple subscribers, required significant custom development and ongoing maintenance effort. The implementation only supported a limited number of subscribers to the event pipeline, with no sustainable pathway for adding more consumers. While attempts were made to reduce coupling through SNS/SQS pairs between services, these solutions were implemented on an ad-hoc basis, lacking standardization and creating additional maintenance overhead. This approach led to redundant work and failed to abstract away common functionality, resulting in an inefficient and hard-to-maintain system.These challenges collectively highlighted the need for a more robust and flexible architectural approach that could better serve the system’s evolving needs while improving reliability, maintainability, and scalability.

Design

Given our requirements and the architectural challenges we faced, we implemented a single-bus, multi-account pattern to optimize our system architecture. In this design, each service team maintains complete ownership and autonomy over their application stack, enabling independent development and deployment cycles. Meanwhile, our DevOps team manages a centralized infrastructure stack that encompasses event bus rules, target configurations, and service integrations. This separation of concerns provides several key benefits:

  1. Clear ownership boundaries: Service teams can focus on their core business logic while leveraging a standardized event infrastructure.
  2. Centralized governance: The DevOps team facilitates consistent event routing patterns, security controls, and monitoring across service integrations.
  3. Simplified operations: A single event bus reduces operational complexity while maintaining logical separation through well-defined routing rules.
  4. Enhanced security: The multi-account structure provides natural isolation boundaries while still enabling controlled cross-account event flows.
  5. Streamlined compliance: Centralized management of data exchange patterns makes it easier to implement and maintain compliance requirements.

While EventBridge provided the foundation, we developed additional components to meet our specific requirements.  Our team built three key components: a schema repository serving as the single source of truth for event definitions, a client library that handles schema validation and provides developer-friendly abstractions, and an infrastructure library offering reusable components for subscriber integration.

Event Schema Repository

Amazon EventBridge’s schema discovery and documentation capabilities provide powerful solutions for managing event-driven architectures. The service automatically captures event structures in the schema registry, maintaining versions as events evolve over time. While EventBridge provides developers with tools to implement validation using external solutions or custom application code, it currently does not include native schema validation capabilities. For our organization’s large-scale event-driven architecture, schema validation was a critical requirement. We evaluated two implementation approaches: a centralized validation service or client-side validation at the publisher/subscriber level. The centralized approach would have required managing additional infrastructure, scaling considerations, and introduced latency through extra network hops. After analyzing these factors alongside our requirements for schema governance and team autonomy, we implemented a custom schema repository with client-side validation.

This architecture prioritizes developer experience through immediate validation feedback while maintaining our standards for schema versioning and release management. The repository serves as the foundation for our event-driven architecture, providing essential capabilities for data governance and quality control. By acting as the single source of truth for event definitions, it enables standardized validation across clients, enforces data quality checks, establishes clear ownership boundaries, and maintains comprehensive audit trails for schema changes. Publishers and subscribers leverage these schemas to maintain data consistency and compatibility as their services evolve. The repository has become instrumental in facilitating efficient cross-team collaboration through self-service schema discovery, documentation, and automated validation during development. It maintains a comprehensive registry of event publishers and their corresponding subscribers, providing clear visibility into event flow patterns and dependencies across the system. Teams can quickly manage schema evolution with clear deprecation policies and migration paths, while the system helps detect breaking changes early in the development cycle. This collaborative approach has significantly improved team velocity and reduced integration issues between services.

{
    "$schema": "http://json-schema.org/draft-04/schema#",
    "$id": "/resource/event/schema/EventV1.json",
    "title": "EventV1",
    "description": "Schema for a simple event.",
    "type": "object",
    "properties": {
        "id": {
            "description": "Id of the event.",
            "type": "string"
        },
        "type": {
            "description": "Type of the event.",
            "$ref": "EventType.json"
        },
        "time": {
            "description": "Time at which the event occurred. It uses ISO 8601 Date Time Format. Reference: https://www.iso.org/iso-8601-date-and-time-format.html",
            "type": "string",
            "format": "date-time"
        },
        "publisher": {
            "description": "Publisher of the event.",
            "$ref": "../core/Publisher.json"
        }
    },
    "required": [
        "id",
        "type",
        "time",
        "publisher"
    ]
}

Client Library

The client library serves as a crucial component for both publishers and subscribers, streamlining their integration with the central event bus. At its core, the library leverages our Event Schema Repository, generating code bindings at build time to provide developers with type-safe and intuitive interfaces for event creation and handling. This approach significantly enhances developer productivity by offering straightforward and convenient methods to construct events and interact with the bus, reducing the likelihood of errors and improving code readability.

A key feature of the client library is its built-in validation mechanism. By utilizing the schemas from our local repository, the library performs thorough validation of events before they are published. This proactive approach catches potential issues early in the development cycle, making sure that only well-formed events conforming to the agreed-upon schemas make it to the event bus. Once validated, the library handles the serialization process and manages the actual publishing of events to the bus, abstracting and simplifying data transformation and transport.

For subscribers, the client library offers equally valuable functionality. It seamlessly handles the deserialization of incoming events, presenting them to the subscribing services in a readily usable format. This feature saves development time and reduces the risk of parsing errors, allowing teams to focus on business logic rather than data handling intricacies. By providing these comprehensive capabilities, our client library has become an indispensable tool in our event-driven network, promoting consistency, reliability, and efficiency across our microservices architecture.

Subscriber Constructs Library

We developed a subscriber constructs library using AWS Cloud Development Kit (CDK) to simplify and standardize the integration process with our central event bus. This library abstracts the setup and management of underlying infrastructure required for event consumption, enabling teams to focus on their core business logic rather than infrastructure configuration details.

The library automates the creation of essential components required for reliable event processing. It provisions a dedicated event bus within the subscriber’s account, establishes the necessary IAM roles and permissions for secure cross-account communication with the central event bus, and configures standardized monitoring and alerting for event processing. This automation not only reduces the potential for configuration errors but also facilitates consistent implementation of our architectural patterns across different teams.

/**
 * Subscriber implementation to provision necessary AWS infrastructure.
 *
 */
const subscription = new Subscription(scope, id, {
    name: "DeliveryService", // Name of your application
    application: {
       region: Region.US_EAST_1, // Region of your Application
    },
});

Conclusion

Amazon Key team’s journey to modernize their architecture and build a resilient, event-driven solution exemplifies the powerful benefits of leveraging AWS EventBridge and adopting a well-designed event-driven architecture. By addressing the challenges of service coupling, loose event schemas, and inconsistent event routing, the team was able to transform their system into a more reliable, scalable, and maintainable resource. The key architectural patterns and components they implemented have had a significant impact on their ability to deliver innovative solutions to their customers.

Reliability and Scale:

  • Built a decoupled event system processing 2000 events/second with 99.99% success rate
  • Achieved consistent 80ms p90 latency from ingestion to target invocation across 14M subscriber calls
  • Avoided the need for new infrastructure for event exchange through standardized event routing
  • Enabled migration of existing complex interdependencies to event-driven architecture

Developer Experience:

  • Reduced service integration time for new use cases from five days to one day (80% improvement)
  • New event onboarding on the Custom Event Schema repository now takes four hours, down from 48 hours
  • Publisher/subscriber integration completed in eight hours, previously took 40 hours
  • Standardized client library addressed 90% of common integration errors

Security and Governance :

  • Single control plane manages 100% of event bus infrastructure
  • Automated security compliance checks catch 100% of unauthorized data exchange patterns
  • Real-time monitoring dashboard tracks every event flow and schema change
  • Schema repository provides complete audit trail for system modifications

The solutions developed by the Amazon Key team provide a blueprint for other organizations looking to modernize their architectures and leverage the power of event-driven design patterns. By adopting similar architectural patterns and components, such as the schema repository and client libraries, other organizations can be empowered to achieve similar benefits.


About the authors

AWS Weekly Roundup: Amazon Bedrock agent workflows, Amazon SageMaker private connectivity, and more (February 2, 2026)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-agent-workflows-amazon-sagemaker-private-connectivity-and-more-february-2-2026/

Over the past week, we passed Laba festival, a traditional marker in the Chinese calendar that signals the final stretch leading up to the Lunar New Year. For many in China, it’s a moment associated with reflection and preparation, wrapping up what the year has carried, and turning attention toward what lies ahead.

Looking forward, next week also brings Lichun, the beginning of spring and the first of the 24 solar terms. In Chinese tradition, spring is often seen as the season when growth begins and new cycles take shape. There’s a common saying that “a year’s plans begin in spring,” capturing the idea that this is a time to set one’s direction and start fresh.

Last week’s launches
Here are the launches that got my attention this week:

  • Amazon Bedrock enhances support for agent workflows with server-side tools and extended prompt caching – Amazon Bedrock introduced two updates that improve how developers build and operate AI agents. The Responses API now supports server-side tool use, so agents can perform actions such as web search, code execution, and database updates within AWS security boundaries. Bedrock also adds a 1-hour time-to-live (TTL) option for prompt caching, which helps improve performance and reduce the cost for long-running, multi-turn agent workflows. Server-side tools are available with OpenAI GPT OSS 20B and 120B models, and the 1-hour prompt caching TTL is generally available for select Claude models by Anthropic in Amazon Bedrock.
  • Amazon SageMaker Unified Studio adds private VPC connectivity with AWS PrivateLinkAmazon SageMaker Unified Studio now supports AWS PrivateLink, providing private connectivity between your VPC and SageMaker Unified Studio without routing customer data over the public internet. With SageMaker service endpoints onboarded into a VPC, data traffic remains within the AWS network and is governed by IAM policies, supporting stricter security and compliance requirements.
  • Amazon S3 adds support for changing object encryption without data movementAmazon S3 now supports changing the server-side encryption type of existing encrypted objects without moving or re-uploading data. Using the UpdateObjectEncryption API, you can switch from SSE-S3 to SSE-KMS, rotate customer -managed AWS Key Management Service (AWS KMS) keys, or standardize encryption across buckets at scale with S3 Batch Operations while preserving object properties and lifecycle eligibility.
  • Amazon Keyspaces introduces table pre-warming for predictable high-throughput workloads – Amazon Keyspaces (for Apache Cassandra) now supports table pre-warming, which helps you proactively set warm throughput levels so tables can handle high read and write traffic instantly without cold-start delays. Pre-warming helps reduce throttling during sudden traffic spikes, such as product launches or sales events, and works with both on-demand and provisioned capacity modes, including multi-Region tables. The feature supports consistent, low-latency performance while giving you more control over throughput readiness.
  • Amazon DynamoDB MRSC global tables integrate with AWS Fault Injection ServiceAmazon DynamoDB multi-Region strong consistency (MRSC) global tables now integrate with AWS Fault Injection Service. With this integration, you can simulate Regional failures, test replication behavior, and validate application resiliency for strongly consistent, multi-Region workloads.

Additional updates
Here are some additional projects, blog posts, and news items that I found interesting:

  • Building zero-trust access across multi-account AWS environments with AWS Verified Access – This post walks through how to implement AWS Verified Access in a centralized, shared-services architecture. It shows how to integrate with AWS IAM Identity Center and AWS Resource Access Manager (AWS RAM) to apply zero trust access controls at the application layer and reduce operational overhead across multi-account AWS environments.
  • Amazon EventBridge increases event payload size to 1 MB – Amazon EventBridge now supports event payloads up to 1 MB, an increase from the previous 256 KB limit. This update helps event-driven architectures carry richer context in a single event, including complex JSON structures, telemetry data, and machine learning (ML) or generative AI outputs, without splitting payloads or relying on external storage.
  • AWS MCP Server adds deployment agent SOPs (preview) – AWS introduced deployment standard operating procedures (SOPs) that AI agents can deploy web applications to AWS from a single natural language prompt in MCP -compatible integrated development environments (IDEs) and command line interfaces (CLIs) such as Kiro, Cursor, and Claude Code. The agent generates AWS Cloud Development Kit (AWS CDK) infrastructure, deploys AWS CloudFormation stacks, and sets up continuous integration and continuous delivery (CI/CD) workflows following AWS best practices. The preview supports frameworks including React, Vue.js, Angular, and Next.js.
  • AWS Network Firewall adds generation AI traffic visibility with web category filtering – AWS Network Firewall now provides visibility into generative AI application traffic through predefined web categories. You can use these categories directly in firewall rules to govern access to generative AI tools and other web services. When combined with TLS inspection, category-based filtering can be applied at the full URL level.
  • AWS Lambda adds enhanced observability for Kafka event source mappingsAWS Lambda introduced enhanced observability for Kafka event source mappings, providing Amazon CloudWatch Logs and metrics to monitor event polling configuration, scaling behavior, and event processing state. The update improves visibility into Kafka-based Lambda workloads, helping teams diagnose configuration issues, permission errors, and function failures more efficiently. The capability supports both Amazon Managed Streaming for Apache Kafka (Amazon MSK) and self-managed Apache Kafka event sources.
  • AWS CloudFormation 2025 year in review – This year-in-review post highlights CloudFormation updates delivered throughout 2025, with a focus on early validation, safer deployments, and improved developer workflows. It covers enhancements such as improved troubleshooting, drift-aware change sets, stack refactoring, StackSets updates, and new -IDE and AI -assisted tooling, including the CloudFormation language server and the Infrastructure as Code (IaC) MCP server.

Upcoming AWS events
Check your calendars so that you can sign up for this upcoming event:

AWS Community Day Romania (April 23–24, 2026) – This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.

If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.

Check back next Monday for another Weekly Roundup.

betty

AWS CloudFormation 2025 Year In Review

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/aws-cloudformation-2025-year-in-review/

AWS CloudFormation enables you to model and provision your cloud application infrastructure as code-base templates. Whether you prefer writing templates directly in JSON or YAML, or using programming languages like Python, Java, and TypeScript with the AWS Cloud Development Kit (CDK), CloudFormation and CDK provide the flexibility you need. For organizations adopting multi-account strategies, CloudFormation StackSets offers a powerful capability to deploy resources across multiple regions and accounts in parallel.

In 2025, we delivered a comprehensive set of major enhancements focused on three core areas: reducing dev-test cycle through early validation, improving deployment safety with improved configuration drift management, and integrating IaC context to AI-powered development tools.

These launches address common pain points in infrastructure development workflows, from catching deployment errors before resource provisioning to managing configuration drift systematically. The features span the entire development lifecycle, from template authoring in your IDE to multi-account deployments at scale.

This blog provides an overview of the key capabilities we launched in 2025 and how they improve your infrastructure development workflow.

Accelerating Development Cycles

Early Validation & Enhanced Troubleshooting: Pre-Deployment Error Detection

CloudFormation now validates your templates during change set (preview of infrastructure changes before deployment) creation, catching common deployment errors before resource provisioning begins. The validation checks for invalid property syntax, resource name conflicts with existing resources in your account, and S3 bucket emptiness constraints on delete operations.

Figure 1: Pre-deployment validations view

Figure 1: Pre-deployment validations view

When validation fails, the change set status shows ‘FAILED’ with detailed information about each issue, including the property path where problems occur. This early feedback helps you fix issues faster rather than waiting for deployment failures.

Figure 2: CloudFormation Validation of Invalid ENUM value for nested property
Figure 2: Validation of Invalid ENUM value for nested property

Improved Deployment troubleshooting

For runtime errors that occur during deployment, every stack operation now receives a unique operation ID. You can filter stack events by operation ID to quickly identify root causes, reducing troubleshooting time from minutes to seconds. The new describe-events API provides grouped access to events. You can query events for a specific operation, filter to FAILED status events, and extract the root cause without parsing through the entire stack event history.

Figure 3: New CloudFormation stack operation pageFigure 3: New CloudFormation stack operation page
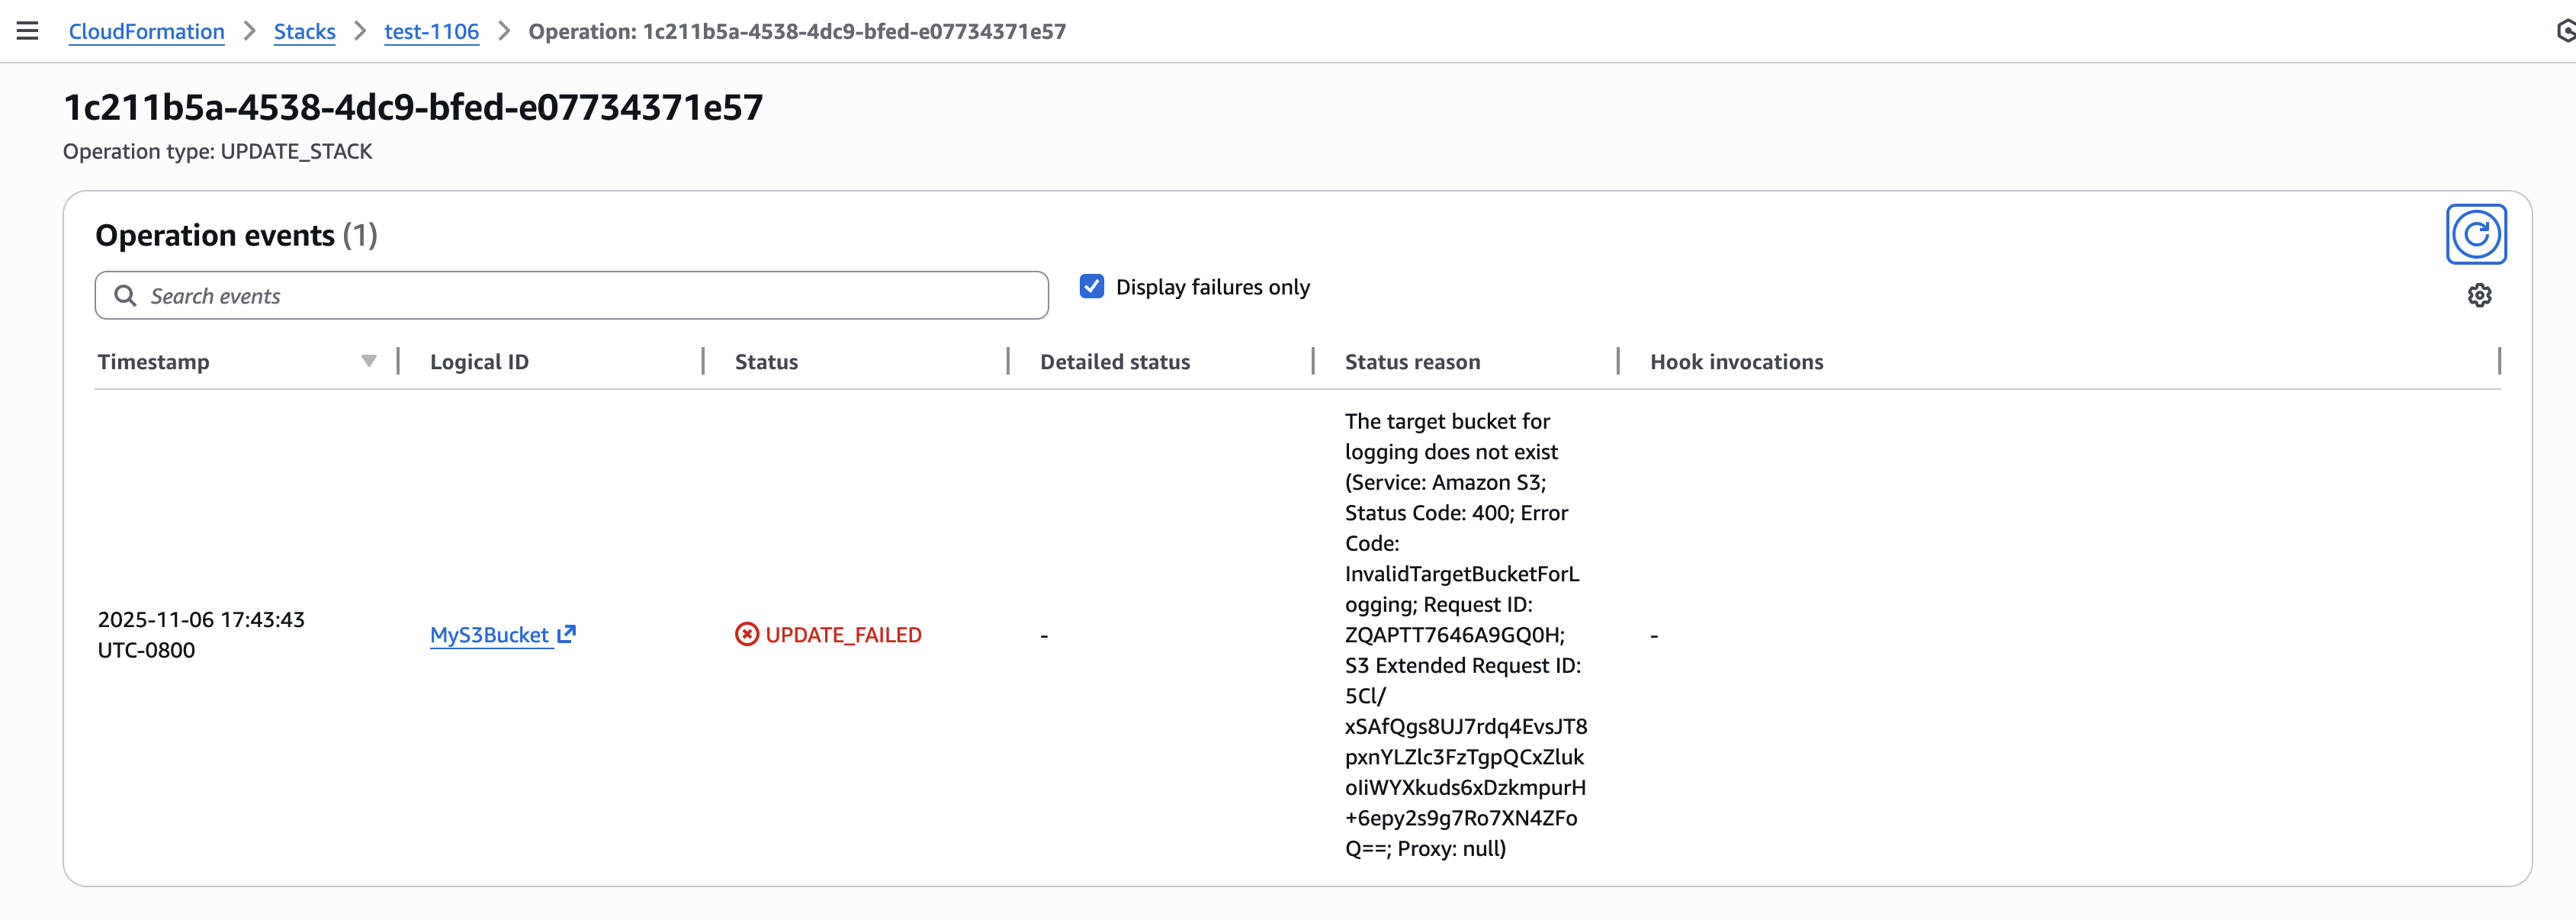
Figure 4: Filter operation failure root causes

Learn more:

CloudFormation IDE Experience: Language Server Protocol Integration

We launched the AWS CloudFormation Language Server, bringing end-to-end infrastructure development directly into your IDE. Available through the AWS Toolkit for Visual Studio Code, Kiro, and other compatible IDEs, this capability transforms how you author CloudFormation templates.

Figure 1: Filter operation failure root causes

Figure 1: Initializing a CloudFormation project with environment configuration

The Language Server provides context-aware auto-completion that understands CloudFormation semantics. When you define resources, it suggests only required properties automatically, while optional properties appear on hover. Built-in validation catches issues before deployment integrating early validation capabilities, flagging invalid resource properties, missing IAM permissions, and security policy violations using CloudFormation Guard.

Figure 2: Hover information displaying optional properties and their documentation

The drift-aware deployment view highlights differences between your template and deployed infrastructure, helping you spot configuration changes made outside CloudFormation. The Language Server also provides semantic navigation features, go-to-definition for logical IDs, find-all-references for resource dependencies, and hover documentation that pulls from the CloudFormation resource specification. These features work across intrinsic functions like !Ref, !GetAtt, and !Sub, understanding the CloudFormation template structure. By integrating validation and real-time feedback directly into your authoring experience, the Language Server keeps you in flow state, reducing context switching between your IDE, AWS Console, and documentation.

Figure 3: Type-aware completions for intrinsic functions like !GetAtt & !Ref

Learn more:

Stack Refactoring: Adapt your infrastructure to your organization evolution

Stack Refactoring enables you to reorganize your CloudFormation and CDK infrastructure without disrupting deployed resources. You can move resources between stacks, rename logical IDs, and decompose monolithic stacks into focused components while maintaining resource stability and operational state.

Whether you’re modernizing legacy stacks, aligning infrastructure with evolving architectural patterns, or improving long-term maintainability, Stack Refactoring adapts your CloudFormation and CDK organization to changing requirements. The console and CDK experience, launched this year, extends the earlier CLI capability, making refactoring accessible through your preferred interface.

Provide a description to help you identify your stack refactor.

Learn more:
Blog Post – Refactor CloudFormation from Console
Blog Post – Refactor CDK

Safer Deployments

Drift-Aware Change Sets

Configuration drift occurs when infrastructure managed by CloudFormation is modified through the AWS Console, SDK, or CLI. Drift-aware change sets address this challenge by providing a three-way comparison between your new template, last-deployed template, and actual infrastructure state.

Examine the drift-aware change set to see the dangerous memory reduction that would occur

Examine the drift-aware change set to see the dangerous memory reduction that would occur

Figure 4: Examine the drift-aware change set to see the dangerous memory reduction that would occur

This capability helps you prevent unexpected overwrites of drift. If your change set preview shows unintended changes, you can update your template values and recreate the change set before deployment. During execution, CloudFormation matches resource properties with template values and recreates resources deleted outside of CloudFormation.

Drift-aware change sets enable you to systematically revert drift and keep infrastructure in sync with templates, strengthening reproducibility for testing and disaster recovery while maintaining your security posture.

Learn more:

Enforcing Proactive Controls

CloudFormation Hooks: Control Catalog with Hooks

AWS CloudFormation Hooks now supports managed proactive controls, enabling customers to validate resource configurations against AWS best practices without writing custom Hooks logic. Customers can select controls from the AWS Control Tower Controls Catalog and apply them during CloudFormation operations. When using CloudFormation, customers can configure these controls to run in warn mode, allowing teams to test controls without blocking deployments and giving them the flexibility to evaluate control behavior before enforcing policies in production. This significantly reduces setup time, eliminates manual errors, and ensures comprehensive governance coverage across your infrastructure.

AWS also introduced a new Hooks Invocation Summary page in the CloudFormation console. This centralized view provides a complete historical record of Hooks activity, showing which controls were invoked, their execution details, and outcomes such as pass, warn, or fail. This simplifies compliance reporting issues faster.

With this launch, customers can now leverage AWS-managed controls as part of their provisioning workflows, eliminating the overhead of writing and maintaining custom logic. These controls are curated by AWS and aligned with industry best practices, helping teams enforce consistent policies across all environments. The new summary page delivers essential visibility into Hook invocation history, enabling faster issue resolution and streamlined compliance reporting.

Learn more:

Scaling Multi-Account Infrastructure

StackSets Deployment Ordering

Figure : Example of a multi-region AWS CloudFormation StackSet architecture with an administrative account and target accounts

CloudFormation StackSets now supports deployment ordering for auto-deployment mode, enabling you to define the sequence in which stack instances automatically deploy across accounts and regions. This capability coordinates complex multi-stack deployments where foundational infrastructure must be provisioned before dependent application components.

Figure : CloudFormation StackSets Console – Auto-deployment options view

When creating or updating a StackSet, you can specify up to 10 dependencies per stack instance using the DependsOn parameter in the AutoDeployment configuration. StackSets automatically orchestrates deployments based on your defined relationships. For example, you can ensure networking and security stack instances complete deployment before application stack instances begin, preventing deployment failures due to missing dependencies.

StackSets includes built-in cycle detection to prevent circular dependencies and provides error messages to help resolve configuration issues. This feature is available at no additional cost in all AWS Regions where CloudFormation StackSets is available.

Learn more:

AI-Powered Infrastructure Development

AWS IaC Server

We introduced the AWS Infrastructure-as-Code (IaC) MCP Server, bridging AI assistants with your AWS infrastructure development workflow. Built on the Model Context Protocol (MCP), this server enables AI assistants like Kiro CLI, Claude, or Cursor to help you search CloudFormation and CDK documentation, validate templates, troubleshoot deployments, and follow best practices, all while maintaining the security of local execution.

Figure 1: Kiro-CLI with AWS IaC MCP server

Figure 1: Kiro-CLI with AWS IaC MCP server

The IaC MCP Server provides nine specialized tools organized into two categories. Remote documentation search tools connect to AWS knowledge bases to retrieve up-to-date information about CloudFormation resources, CDK APIs, and implementation guidance. Local validation and troubleshooting tools run entirely on your machine, performing syntax validation with cfn-lint, security checks with CloudFormation Guard, and deployment failure analysis with integrated CloudTrail events.

Figure 4: Validate my CloudFormation template with AWS IaC MCP Server

Figure 4: Validate my CloudFormation template with AWS IaC MCP Server

Key Use Cases

  1. Intelligent Documentation Assistant

Instead of manually searching through documentation, ask your AI assistant natural language questions:

“How do I create an S3 bucket with encryption enabled in CDK?”

The server searches CDK best practice and samples, returning relevant code examples and explanations.

     2. Proactive Template Validation

Before deploying infrastructure changes:

User: “Validate my CloudFormation template and check for security issues”

AI Agent: [Uses validate_cloudformation_template and check_cloudformation_template_compliance]

“Found 2 issues: Missing encryption on EBS volumes,

and S3 bucket lacks public access block configuration”

 3. Rapid Deployment Troubleshooting

When a stack deployment fails:

User: “My stack ‘stack_03’ in us-east-1 failed to deploy. What happened?”

AI Agent: [Uses troubleshoot_stack_deployment with CloudTrail integration]

“The deployment failed due to insufficient IAM permissions.

CloudTrail shows AccessDenied for ec2:CreateVpc.

You need to add VPC permissions to your deployment role.”

     4. Learning and Exploration

New to AWS CDK? The server helps you discover constructs and patterns:

User: “Show me how to build a serverless API”

AI Agent: [Searches CDK constructs and samples]

“Here are three approaches using API Gateway + Lambda…”

Learn more: Detailed Blog Post

Learn more

Here are some resources to help you get started learning and using CloudFormation to manage your cloud infrastructure:

Conclusion

As we begin 2026, our focus remains on making infrastructure deployment faster, safer, and more manageable. The launches in 2025 reflect our commitment to solving real customer challenges and improving the CloudFormation developer experience. From intelligent IDE integrations to AI-powered assistance, these capabilities help you build infrastructure with greater confidence and efficiency.

We encourage you to try these features and share your feedback. For detailed information about any of these launches, visit our documentation or check out the AWS DevOps Blog.

Blog Author Bio:

Idriss Laouali Abdou

Idriss is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Introducing the AWS Infrastructure as Code MCP Server: AI-Powered CDK and CloudFormation Assistance

Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/introducing-the-aws-infrastructure-as-code-mcp-server-ai-powered-cdk-and-cloudformation-assistance/

Streamline your AWS infrastructure development with AI-powered documentation search, validation, and troubleshooting

Introduction

Today, we’re excited to introduce the AWS Infrastructure-as-Code (IaC) MCP Server, a new tool that bridges the gap between AI assistants and your AWS infrastructure development workflow. Built on the Model Context Protocol (MCP), this server enables AI assistants like Kiro CLI, Claude or Cursor to help you search AWS CloudFormation and Cloud Development Kit (CDK) documentation, validate templates, troubleshoot deployments, and follow best practices – all while maintaining the security of local execution.

Whether you’re writing AWS CloudFormation templates or AWS Cloud Development Kit (CDK) code, the IaC MCP Server acts as an intelligent companion that understands your infrastructure needs and provides contextual assistance throughout your development lifecycle.

The Model Context Protocol (MCP) is an open standard that enables AI assistants to securely connect to external data sources and tools. Think of it as a universal adapter that lets AI models interact with your development tools while keeping sensitive operations local and under your control.

The IaC MCP Server provides nine specialized tools organized into two categories:

Remote Documentation Search Tools

These tools connect to the AWS Knowledge MCP backend to retrieve relevant, up-to-date information:

  1.  search_cdk_documentation
    Search the AWS CDK knowledge base for APIs, concepts, and implementation guidance.
  2. search_cdk_samples_and_constructs
    Discover pre-built AWS CDK constructs and patterns from the AWS Construct Library.
  3. search_cloudformation_documentation
    Query CloudFormation documentation for resource types, properties, and intrinsic functions.
  4. read_cdk_documentation_page
    Retrieve and read full documentation pages returned from searches or provided URLs.

Local Validation and Troubleshooting Tools

These tools run entirely on your machine

  1. cdk_best_practices
    Access a curated collection of AWS CDK best practices and design principles.
  2. validate_cloudformation_template
    Perform syntax and schema validation using cfn-lint to catch errors before deployment.
  3. check_cloudformation_template_compliance
    Run security and compliance checks against your templates using AWS Guard rules and cfn-guard.
  4. troubleshoot_cloudformation_deployment
    Analyze CloudFormation stack deployment failures with integrated CloudTrail event analysis. This tool will use your AWS credentials to analyze your stack status.
  5. get_cloudformation_pre_deploy_validation_instructions
    Returns instructions for CloudFormation’s pre-deployment validation feature, which validates templates during change set creation.

Key Use Cases

  1. Intelligent Documentation Assistant

Instead of manually searching through documentation, ask your AI assistant natural language questions:

“How do I create an S3 bucket with encryption enabled in CDK?”

The server searches CDK best practic and samples, returning relevant code examples and explanations.

     2. Proactive Template Validation

Before deploying infrastructure changes:

User: “Validate my CloudFormation template and check for security issues”

AI Agent: [Uses validate_cloudformation_template and check_cloudformation_template_compliance]

“Found 2 issues: Missing encryption on EBS volumes,

and S3 bucket lacks public access block configuration”

 3. Rapid Deployment Troubleshooting

When a stack deployment fails:

User: “My stack ‘stack_03’ in us-east-1 failed to deploy. What happened?”

AI Agent: [Uses troubleshoot_stack_deployment with CloudTrail integration]

“The deployment failed due to insufficient IAM permissions.

CloudTrail shows AccessDenied for ec2:CreateVpc.

You need to add VPC permissions to your deployment role.”

     4. Learning and Exploration

New to AWS CDK? The server helps you discover constructs and patterns:

User: “Show me how to build a serverless API”

AI Agent: [Searches CDK constructs and samples]

“Here are three approaches using API Gateway + Lambda…”

Architecture and Security

Security Design

Local Execution: The MCP server runs entirely on your local machine using uv (the fast Python package manager). No code or templates are sent to external services except for documentation searches.

AWS Credentials: The server uses your existing AWS credentials (from ~/.aws/credentials, environment variables, or IAM roles) to access CloudFormation and CloudTrail APIs. This follows the same security model as the AWS CLI.

stdio Communication: The server communicates with AI assistants over standard input/output (stdio), with no network ports opened.

Minimal Permissions: For full functionality, the server requires read-only access to CloudFormation stacks and CloudTrail events—no write permissions needed for validation and troubleshooting workflows.

Getting Started

Prerequisites

  • Python 3.10 or later
    uv package manager
    AWS credentials configured locally
    MCP-compatible AI client (e.g., Kiro CLI, Claude Desktop)

Configuration

Configure the MCP server in your MCP client configuration. For this blog we will focus on Kiro CLI. Edit .kiro/settings/mcp.json):

{
  "mcpServers": {
    "awslabs.aws-iac-mcp-server": {
      "command": "uvx",
      "args": ["awslabs.aws-iac-mcp-server@latest"],
      "env": {
        "AWS_PROFILE": "your-named-profile",
        "FASTMCP_LOG_LEVEL": "ERROR"
      },
      "disabled": false,
      "autoApprove": []
    }
  }
}

Security Considerations

Privacy Notice: This MCP server executes AWS API calls using your credentials and shares the response data with your third-party AI model provider (e.g., Amazon Q, Claude Desktop, Cursor, VS Code). Users are responsible for understanding your AI provider’s data handling practices and ensuring compliance with your organization’s security and privacy requirements when using this tool with AWS resources.

IAM Permissions

The MCP server requires the following AWS permissions:

For Template Validation and Compliance:

  • No AWS permissions required (local validation only)

For Deployment Troubleshooting:

  • cloudformation:DescribeStacks
  • cloudformation:DescribeStackEvents
  • cloudformation:DescribeStackResources
  • cloudtrail:LookupEvents (for CloudTrail deep links)

Example IAM policy:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "cloudformation:DescribeStacks",
        "cloudformation:DescribeStackEvents",
        "cloudformation:DescribeStackResources",
        "cloudtrail:LookupEvents"
      ],
      "Resource": "*"
    }
  ]
}

Example Use Case With Kiro CLI

IMPORTANT: Ensure you have satisfied all prerequisites before attempting these commands.

1. With the mcp.json file correctly set, try to run a sample prompt. In your terminal, run kiro-cli chat to start using Kiro-cli in the CLI.

Figure 1: Kiro-CLI with AWS IaC MCP server

Figure 1: Kiro-CLI with AWS IaC MCP server

Scenarios:

  • “What are the CDK best practices for Lambda functions?”

Figure 2 Search the CDK best practices for Lambda functions

Figure 2: Search the CDK best practices for Lambda functions

  • “Search for CDK samples that use DynamoDB with Lambda”

Figure 3: Search for CDK samples that use DynamoDB with Lambda

Figure 3: Search for CDK samples that use DynamoDB with Lambda

  • “Validate my CloudFormation template at ./template.yaml”

Figure 4: Validate my CloudFormation template with AWS IaC MCP Server

Figure 4: Validate my CloudFormation template with AWS IaC MCP Server

  • “Check if my template complies with security best practices”

Figure 5: Check if my template complies with security best practices with AWS IaC MCP Server

Figure 5: Check if my template complies with security best practices with AWS IaC MCP Server

Best Practices

  • Start with Documentation Search: Before writing code, search for existing constructs and patterns
  • Validate Early and Often: Run validation tools before attempting deployment
  • Check Compliance: Use check_template_compliance to catch security issues during development
  • Leverage CloudTrail: When troubleshooting, the CloudTrail integration provides detailed failure context
  • Follow CDK Best Practices: Use the cdk_best_practices tool to align with AWS recommendations

What’s Next?

The IAC MCP Server represents a new paradigm in the AI agentic workflow infrastructure development – one where AI assistants understand your tools, help you navigate complex documentation, and provide intelligent assistance throughout the development lifecycle.

Get Involved

The AWS IaC MCP Server is available now:

  • Documentation and GitHub Repository: aws-iac-mcp-server
  • Feedback: We welcome issues and pull requests! Or respond to our IaC survey here.

Ready to supercharge your infrastructure as code development? Install the IaC MCP Server today and experience AI-powered assistance for your AWS CDK and CloudFormation workflows.

Have questions or feedback? Reach out to the blog authors on the AWS Developer Forums.

About Authors

Idriss Laouali Abdou

Idriss is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Brian Terry

Brian Terry, Senior WW Data & AI PSA, is an innovation leader with more than 20 years of experience in technology and engineering. Brian is pursuing a PhD in computer science at the University of North Dakota and has spearheaded generative AI projects, optimized infrastructure scalability, and driven partner integration strategies. He is passionate about leveraging technology to deliver scalable, resilient solutions that foster business growth and innovation.

Introducing AWS CloudFormation Stack Refactoring Console Experience: Reorganize Your Infrastructure Without Disruption

Post Syndicated from Brian Terry original https://aws.amazon.com/blogs/devops/introducing-aws-cloudformation-stack-refactoring-reorganize-your-infrastructure-without-disruption/

AWS CloudFormation models and provisions cloud infrastructure as code, letting you manage entire lifecycle operations through declarative templates. Stack Refactoring console experience, announced today, extends the AWS CLI experience launched earlier. Now, you move resources between stacks, rename logical IDs, and decompose monolithic templates into focused components without touching the underlying infrastructure using the CloudFormation console. Your resources maintain stability and operational state throughout the reorganization. Whether you’re modernizing legacy stacks, aligning infrastructure with evolving architectural patterns, or improving long-term maintainability, Stack Refactoring adapts your CloudFormation stacks organization to changing requirements without forcing disruptive workarounds.

Stack Refactoring enables you to move resources between stacks, rename logical resource IDs, and split monolithic stacks into smaller, more manageable components—all while maintaining resource stability and preserving your infrastructure’s operational state. If you’re modernizing legacy infrastructure, aligning stack organization with evolving architectural patterns, or improving maintainability across your cloud resources, Stack Refactoring provides the flexibility you need to adapt your CloudFormation organization to changing

How It Works

Stack Refactoring operates through a controlled, multi-phase process designed around resource safety. When you initiate a refactor operation, CloudFormation analyzes both source and destination templates, constructs a detailed execution plan, then orchestrates resource movement without disrupting running infrastructure. Resource mappings define how assets transfer between stacks and how logical IDs should change. CloudFormation handles the orchestration complexity automatically – moving resources from source stacks, updating or creating destination stacks, and preserving all dependency relationships through exports and imports.

Each refactor operation receives a unique Stack Refactor ID for tracking progress, reviewing planned actions before execution, and monitoring the operation from initiation through completion. This preview-then-execute model gives you confidence in complex refactoring scenarios where dependencies span multiple stacks or templates.

Compared to the CLI, the console experience provides an easier way to view refactor actions, get automatic resource mapping, and easily rename logical IDs.

Example Scenario

Scenario 1: Splitting a Monolithic Stack

In this scenario, you have an Amazon Simple Notification Service (SNS) and AWS Lambda Function subscribed to it. As usage patterns evolve, you want to separate the subscriptions into a different stack for better organizational boundaries. You can also rename a resource’s logical ID to improve template clarity or align with naming conventions. Stack Refactoring handles this without recreating the underlying resource.

  1. Create a new template MySNS.yaml using the following :
    # Original stack: MySns
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    
      MyFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
    
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt MyFunction.Arn
          Protocol: lambda
          TopicArn: !Ref Topic
    
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt MyFunction.Arn
          SourceArn: !Ref Topic
    
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
  2. Create a new stack using this MySNS.yaml template:
    aws cloudformation create-stack --stack-name MySns --template-body file://MySNS.yaml --capabilities CAPABILITY_IAM
  3. Create a new template called afterSns.yaml with the content below. This template has your SNS topic in it and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
    # afterSns.yaml - Focused SNS stack
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    Outputs:
      TopicArn:
        Value: !Ref Topic
        Export:
          Name: TopicArn
  4. Create a new template afterLambda.yaml with the following content. This template includes all the resources to create a Lambda subscription to your SNS topic. This template switched the !Ref Topic to use the exported valued by using !ImportValue TopicArn. We are also updating the Logical Resource Id of Lambda function from MyFunction to Function

    AWSTemplateFormatVersion: "2010-09-09"
    Resources:
      Function:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt Function.Arn
          Protocol: lambda
          TopicArn: !ImportValue TopicArn
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt Function.Arn
          SourceArn: !ImportValue TopicArn
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow


  5. Go to stack refactor home page, click on ‘create stack refactor’
    Go to stack refactor home page, click on ‘create stack refactor’
  6. Provide a description to help you identify your stack refactor.
    Provide a description to help you identify your stack refactor.
  7. For this scenario, we are splitting a monolithic stack so select ‘Update the template for an existing stack’ and ‘Choose a stack’ options.
  8. Search and choose the stack MySns that was created in Step 1.
    Search and choose the stack MySns that was created in Step 1.
  9. Upload the afterSns.yaml file
    Upload the afterSns.yaml file
  10. You want to create a new stack to manage the Lambda function and SNS subscription resources. Choose ‘Create a new stack’ and name it ‘LambdaSubscription’.
  11. Upload afterLambda.yaml template file
    Upload afterLambda.yaml template fileIn some scenarios, CloudFormation console can automatically detect logical resource ID renames and pre-fill the mapping for you. The resource mapping is required when there are logical resource ID changes between the original stack and refactored template. Ensure that the mappings are correct before proceeding to the next step.
    In some scenarios, CloudFormation console can automatically detect logical resource ID renames
  12. The stack refactor preview will start generating. Wait for the preview to complete. You can verify actions under Stack 1 and Stack 2. It will show you the action for each resource.
    The stack refactor preview will start generating. Wait for the preview to complete. You can verify actions under Stack 1 and Stack 2. It will show you the action for each resource.
  13. You can also preview the new Stack refactored templates
    You can also preview the new Stack refactored templates
  14. Once you verify the details, go ahead and Execute Refactor. You should be redirected to the stack refactor details.
  15. Once the Stack refactor execution is complete you can view the actions and templates for each of the stacks in your stack refactor.
    Once the Stack refactor execution is complete you can view the actions and templates for each of the stacks in your stack refactor.

Scenario 2: Move resources across multiple stacks.

This scenario demonstrates how to refactor resources across three stacks using the AWS CLI, then review and execute the operation in the CloudFormation console.

  1. Create a new template many-stacks-original.yaml and create a new stack named ‘RefactorManyStacks’ using AWS CLI. This template contains SNS topic (IngestTopic),Lambda function(IngestFunction) and SNS subscription.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      IngestTopic:
        Type: AWS::SNS::Topic
    
      IngestFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt IngestFunctionRole.Arn
          Timeout: 30
    
      IngestSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt IngestFunction.Arn
          Protocol: lambda
          TopicArn: !Ref IngestTopic
    
      IngestFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt IngestFunction.Arn
          SourceArn: !Ref IngestTopic
    
      IngestFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
  2. Create another template many-stacks-original-1.yaml and run the AWS CLI command to create a new stack ‘RefactorManyStacks1’. This template creates another SNS topic (UserTopic), Lambda function (UserFunction) and SNS subscription.
    aws cloudformation create-stack --stack-name RefactorManyStacks --template-body file://many-stacks-original.yaml --capabilities CAPABILITY_IAM
  3. Create a new template many-stacks-original-2.yaml and run the AWS CLI command to create the stack RefactorManyStacks2. This template will also create SNS topic (ConsumerTopic), Lambda function (ConsumerFunction) and SNS subscription to lambda function.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      ConsumerTopic:
        Type: AWS::SNS::Topic
    
      ConsumerFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-2
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt ConsumerFunctionRole.Arn
          Timeout: 30
    
      ConsumerSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt ConsumerFunction.Arn
          Protocol: lambda
          TopicArn: !Ref ConsumerTopic
    
      ConsumerFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt ConsumerFunction.Arn
          SourceArn: !Ref ConsumerTopic
    
      ConsumerFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-2"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
    aws cloudformation create-stack --stack-name RefactorManyStacks2 --template-body file://many-stacks-original-2.yaml --capabilities CAPABILITY_IAM

Once all 3 stacks have been created successfully. Create refactored templates.

  1. Create new template many-stacks-refactored.yaml This refactored template only contains SNS topic named IngestTopic and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      IngestTopic:
        Type: AWS::SNS::Topic
    Outputs:
      IngestTopicArn:
        Value: !Ref IngestTopic
        Export:
          Name: IngestTopicArn
  2. Create another template many-stacks-refactored-1.yaml. This template **** has the SNS topic UserTopic and contains the IngestFunction and IngestSubscription and required IAM resources from ‘RefactorManyStacks’. This template switched the !Ref IngestTopic to use the exported valued by using !ImportValue IngestTopicArn. This refactored template also a new export in it that will export the UserTopic ARN.
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      UserTopic:
        Type: AWS::SNS::Topic
      IngestFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt IngestFunctionRole.Arn
          Timeout: 30
    
      IngestSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt IngestFunction.Arn
          Protocol: lambda
          TopicArn: !ImportValue IngestTopicArn
    
      IngestFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt IngestFunction.Arn
          SourceArn: !ImportValue IngestTopicArn
    
      IngestFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
    Outputs:
      UserTopicArn:
        Value: !Ref UserTopic
        Export:
          Name: UserTopicArn
  3. Create another template many-stacks-refactored-2.yaml. This template has the Consumer* resources along with Lambda function (UserFunction) and SNS subscription (UserSubscription). The template is using exported value from many-stacks-refactored-1.yaml by using !ImportValue UserTopicArn

    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      ConsumerTopic:
        Type: AWS::SNS::Topic
    
      ConsumerFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-2
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt ConsumerFunctionRole.Arn
          Timeout: 30
    
      ConsumerSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt ConsumerFunction.Arn
          Protocol: lambda
          TopicArn: !Ref ConsumerTopic
    
      ConsumerFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt ConsumerFunction.Arn
          SourceArn: !Ref ConsumerTopic
    
      ConsumerFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-2"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
      UserFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: many-stack-my-function-1
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt UserFunctionRole.Arn
          Timeout: 30
    
      UserSubscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt UserFunction.Arn
          Protocol: lambda
          TopicArn: !ImportValue UserTopicArn
    
      UserFunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt UserFunction.Arn
          SourceArn: !ImportValue UserTopicArn
    
      UserFunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:many-stack-my-function-1"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow


  4. Start the stack refactor using AWS CLI.
    aws cloudformation create-stack-refactor --stack-definitions StackName=RefactorManyStacks,TemplateBody@=file://many-stacks-refactored.yaml StackName=RefactorManyStacks1,TemplateBody@=file://many-stacks-refactored-1.yaml StackName=RefactorManyStacks2,TemplateBody@=file://many-stacks-refactored-2.yaml --description "three stack refactor"
  5. Go to stack CloudFormation console and go to ‘Stack refactor’ homepage, click on the stack refactor you just created.
    Go to stack CloudFormation console and go to ‘Stack refactor’ homepage, click on the stack refactor you just created.
  6. Review actions for each resource and each stack. You can choose individual stacks from drop down.
    Review actions for each resource and each stack. You can choose individual stacks from drop down.
  7. Once you’re ready to execute the stack refactor, click on ‘Execute stack refactor’ and input the confirmation text.
    Once you’re ready to execute the stack refactor, click on ‘Execute stack refactor’ and input the confirmation text.
  8. Wait for stack refactor execution to finish.
    Wait for stack refactor execution to finish.
  9. Click on the stack in the details to navigate to the stack details. You can verify the refactor changes here.
    Click on the stack in the details to navigate to the stack details. You can verify the refactor changes here.

Scenario 3: Move stacks between 2 nested child stacks stacks

This scenario demonstrates how to move resources between child stacks in a nested stack architecture. Upload child stack templates toAmazon Simple Storage Service (Amazon S3), create a parent stack that references them, then use Stack Refactoring to move resources (like a security group) from one child stack to another. The key is to work directly with the child stack names (which CloudFormation auto-generates based on parent stack name and logical IDs) rather than the parent stack itself. After refactoring, update the parent stack to reference the new child template versions in S3.

This approach lets you reorganize nested stack architectures while maintaining the parent-child relationship structure.

  1. Create first child stack template vpc.yaml. This template creates a new Virtual Private Cloud(VPC). Upload this new template file to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'VPC Stack - Contains only VPC'
    
    Resources:
      MyVPC:
        Type: AWS::EC2::VPC
        Properties:
          CidrBlock: 10.0.0.0/16
    
    Outputs:
      VPCId:
        Value: !Ref MyVPC
  2. Create second child stack template resource.yaml . This template will create S3 bucket and EC2 Security Group. Once you create this template file, upload it to an S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: ' Contains security group and S3 bucket'
    
    Resources:
      MySecurityGroup:
        Type: AWS::EC2::SecurityGroup
        Properties:
          GroupDescription: Security group for testing
          SecurityGroupIngress:
            - IpProtocol: tcp
              FromPort: 80
              ToPort: 80
              CidrIp: 0.0.0.0/0
    
      MyS3Bucket:
        Type: AWS::S3::Bucket
    
    Outputs:
      SecurityGroupId:
        Value: !Ref MySecurityGroup
      S3BucketName:
        Value: !Ref MyS3Bucket
  3. Create parent stack template file parent.yaml. Make sure to edit the TemplateURL with your S3 Object URL

    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Parent stack for test'
    
    Resources:
      VPCStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/vpc.yaml
    
      ResourceStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/resource.yaml
    
    Outputs:
      VPCStackName:
        Value: !Ref VPCStack
      ResourceStackName:
        Value: !Ref ResourceStack


  4. Create this new Parent stack using AWS CLI :
    aws cloudformation create-stack --stack-name ParentStack --template-body file://parent.yaml --capabilities CAPABILITY_IAM
  5. We will use stack refactor to move EC2 Security group from ResourceStack to VPCStack.
  6. Create new template file VPCStackAfter.yaml. This template now has VPC and EC2 Security group resources. Upload this template to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: ' VPC Stack AFTER - Contains VPC and security group'
    
    Resources:
      MyVPC:
        Type: AWS::EC2::VPC
        Properties:
          CidrBlock: 10.0.0.0/16
    
      MySecurityGroup:
        Type: AWS::EC2::SecurityGroup
        Properties:
          GroupDescription: Security group for testing
          SecurityGroupIngress:
            - IpProtocol: tcp
              FromPort: 80
              ToPort: 80
              CidrIp: 0.0.0.0/0
    
    Outputs:
      VPCId:
        Value: !Ref MyVPC
      SecurityGroupId:
        Value: !Ref MySecurityGroup
  7. Create ResourceStackAfter.yaml The resource stack will only contain s3 bucket resource. Upload this template to S3 bucket
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Resource Stack AFTER - Contains only S3 bucket'
    
    Resources:
      MyS3Bucket:
        Type: AWS::S3::Bucket
    
    Outputs:
      S3BucketName:
        Value: !Ref MyS3Bucket
  8. Navigate to CloudFormation Console and select Start stack refactor
  9. Add a description for Stack refactor:
    Add a description for Stack refactor:
  10. Choose “Update the template for an existing stack” and select child stack “ParentStack-VPCStack-12345”. Make sure to choose the child stack and not the Root/Parent stack.
    Choose “Update the template for an existing stack” and select child stack “ParentStack-VPCStack-12345”. Make sure to choose the child stack and not the Root/Parent stack.
  11. Upload the new template VPCStackAfter.yaml
    Upload the new template VPCStackAfter.yaml
  12. For Stack2, again select ‘Update the template for an existing stack’ and select to 2nd child stack “ParentStack-ResourceStack-12345”
  13. Upload the template ResourceStackAfter.yaml
    Upload the template ResourceStackAfter.yaml
  14. Review the Stack refactor. Once you have verified all the actions and details choose ‘Execute Refactor’
    Review the Stack refactor. Once you have verified all the actions and details choose ‘Execute Refactor
  15. You can verify the refactor templates.
    stack Console
  16. Lastly, update your ParentStack.yaml to reference the new child template versions in S3 bucket.
    AWSTemplateFormatVersion: '2010-09-09'
    Description: 'Parent stack for test'
    
    Resources:
      VPCStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/VPCStackAfter.yaml
    
      ResourceStack:
        Type: AWS::CloudFormation::Stack
        Properties:
          TemplateURL: https://s3.amazonaws.com/<Bucket-Name>/ResourceStackAfter.yaml
    
    Outputs:
      VPCStackName:
        Value: !Ref VPCStack
      ResourceStackName:
        Value: !Ref ResourceStack

Best Practices

Stack Refactoring offers powerful flexibility, but a few strategic considerations will help ensure smooth operations. Test your refactoring plans in non-production environments first, particularly when working with complex dependency chains or resources that have strict ordering requirements. The preview phase becomes your primary safety mechanism—treat it as a thorough code review, examining each planned action before execution. When moving resources between stacks, pay close attention to cross-stack references. Converting direct references to export/import patterns maintains loose coupling and prevents circular dependencies. CloudFormation will automatically manage these conversions during refactoring, but understanding the resulting architecture helps you avoid introducing fragility into your infrastructure.

For scenarios where you’re emptying a source stack entirely, remember that CloudFormation requires at least one resource per stack. This makes placeholder resources like AWS::CloudFormation::WaitConditionHandle a useful temporary measure—they consume no actual AWS resources and can be safely deleted along with the stack once the refactoring completes.

Document your refactoring decisions alongside the templates themselves. Future maintainers (including yourself in six months) will appreciate understanding why resources were organized in particular ways. Include comments in your templates explaining the reasoning behind stack boundaries and resource groupings.

Consider the operational impact of your refactoring. While resources themselves remain stable, monitoring dashboards, automation scripts, or other tooling that references stack names or logical IDs may need updates. Plan these ancillary changes as part of your refactoring workflow rather than discovering them afterward.

Finally, leverage refactoring as an opportunity to improve template quality more broadly. If you’re already reorganizing resources, consider also updating documentation, standardizing naming conventions, or adding tags for better resource management.

Conclusion

CloudFormation Stack Refactoring transforms how you organize and maintain infrastructure as code, enabling stack architecture to evolve alongside applications and organizational needs. This capability provides the flexibility to restructure without the risk and complexity of traditional resource recreation approaches. Whether you’re breaking apart monolithic stacks, consolidating fragmented infrastructure, or simply renaming resources to match current conventions, Stack Refactoring lets you adapt CloudFormation organization to changing requirements without operational disruption.

To get started, visit the CloudFormation console or explore the AWS CloudFormation API reference for programmatic access patterns. Stack Refactoring is available today in all commercial AWS regions.

Brian Terry

Brian Terry

Brian Terry, Senior WW Data & AI PSA, is an innovation leader with 20+ years of experience in technology and engineering. Pursuing a Ph.D. in Computer Science at the University of North Dakota. Brian has spearheaded generative AI projects, optimized infrastructure scalability, and driven partner integration strategies. He is passionate about leveraging technology to deliver scalable, resilient solutions that foster business growth and innovation

Idriss Louali Abdou

Idriss Laouali Abdou

Idriss Laouali Abdou is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through AWS CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.

Sanchi Halikar

Sanchi Halikar

Sanchi is a Solutions Architect supporting Enterprise customers at AWS. She helps customers design and implement cloud solutions with a focus on DevOps strategies. She specializes in Infrastructure as Code and is passionate about leveraging generative AI in software development

Jamie, AWS IaC console Front-end engineer

Jamie To

Jamie is a Front End Engineer and has been delivering console features to AWS IaC customers for the last 3 years. Outside of work, Jamie enjoys drawing and playing foosball.

Take fine-grained control of your AWS CloudFormation StackSets Deployment with StackSet Dependencies

Post Syndicated from Tanvi Ravindra Malali original https://aws.amazon.com/blogs/devops/take-fine-grained-control-of-your-aws-cloudformation-stacksets-deployment-with-stackset-dependencies/

Introduction

AWS CloudFormation StackSets enable you to deploy CloudFormation stacks across multiple AWS accounts and regions with a single operation, providing centralized management of infrastructure at scale through AWS Organizations integration. In enterprise environments, multiple StackSet often need to deploy in a specific order. For example, networking infrastructure must be ready before applications can deploy successfully.

Architecture diagram showing an Administrator account with a Stack set, and many target accounts with their own stacks, which in turn control other stacks. Demonstrating how a multi account, multi stack architecture can get complicated.

Figure 1: Example of a multi-region AWS CloudFormation StackSet architecture with an administrative account and target accounts

Previously, when multiple StackSets had auto-deployment enabled, they operated independently without coordination. This could cause deployment failures when dependent infrastructure wasn’t ready, forcing customers to implement complex workarounds or disable auto-deployment entirely.

We are announcing StackSets dependencies, a new feature that gives you fine-grained control over the deployment order of your auto-deployed StackSets, elegantly solving these orchestration challenges.

Feature Overview

This new feature introduces the ability to define dependencies between StackSets using the new DependsOn parameter in the AutoDeployment configuration. When accounts move between Organizational Units or are added to your organization, StackSets automatically orchestrates deployments according to your defined sequence, ensuring foundational infrastructure deploys before dependent applications.

Key capabilities include:

  • Dependency Management: Define up to 10 dependencies per StackSet, with up to 100 dependencies per account. For example, if you have 5 StackSets with 5 dependencies each, you have 25 dependencies counting towards the 100 dependency limit. You can request a limit increase through the service quota console.
  • Cycle Detection: Built-in validation prevents circular dependencies with error messages.
  • Cross-Region Support: Dependencies work across regions.
  • Automatic Cleanup: Dependencies are removed when StackSets are deleted or Organizations are deactivated.

How it works

Let’s walk through this feature with a practical example. Consider an infrastructure setup where you have: A central Infrastructure StackSet that creates IAM roles and networking components and multiple Application StackSets that depend on these foundational resources.

With StackSets dependencies, you can make sure the Infrastructure StackSet completes deployment before any Application StackSets begin, preventing deployment failures due to missing dependencies.

Implementation Scenarios

Let’s explore three common scenarios where StackSets Dependencies provides value:

Scenario 1: Foundation-First Deployment

Use Case: You have a foundational Infrastructure StackSet that creates IAM roles and networking components, and multiple Application StackSets that depend on these resources.

Setup:

  • Infrastructure StackSet ARNs (creates IAM roles, VPCs, security groups)
  • App1 StackSet (web application requiring IAM roles)
  • App2 StackSet (API service requiring networking components)
  • No additional permissions are required to use this feature.

Console Experience

The CloudFormation console provides an intuitive interface for managing StackSet dependencies. Log into the AWS console with your credentials, with an IAM user or administrative user, according to your access. Navigate to the Cloudformation service and create a new Stack or add a YAML/JSON template, where you will be configuring dependencies. In the Step 4 of the Create StackSet wizard, you’ll find a new “StackSet dependencies” form field in the Auto-deployment options section. You can use the attribute editor to add StackSet ARNs for dependencies. The console includes input validation for ARN format and helpful alerts about dependency behavior.

Console view showing options to Activate or Deactivate Automatic deployment, and whether to Delete or Retain stacks, and the new feature, Stack set dependencies, and a space to designate a dependent stack set.

Figure 2: CloudFormation StackSets Console – Auto-deployment options view

AWS CLI Implementation:

  1. Create the foundational Infrastructure StackSet:

aws cloudformation create-stack-set \
  --stack-set-name Infrastructure \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://infrastructure-template.yaml \
  --region us-east-1

2. Create App1 with dependency on Infrastructure:

aws cloudformation create-stack-set \
  --stack-set-name App1 \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,\
  DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Infrastructure:uuid \
  --template-body file://app1-template.yaml \
  --region us-east-1

3. Create App2 with dependency on Infrastructure:

aws cloudformation create-stack-set \
  --stack-set-name App2 \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Infrastructure:uuid \
  --template-body file://app2-template.yaml \
  --region us-west-2

Now, when accounts are added to your organization, Infrastructure deploys first, then App1 and App2 deploy in parallel after Infrastructure completes.

Scenario 2: Multi-Dependency Application

Use Case: Your application requires both networking and security components to be ready before deployment.

Setup:

  • Networking StackSet (VPCs, subnets, route tables)
  • Security StackSet (security groups, NACLs, IAM policies)
  • Application StackSet (requires both networking and security)

Implementation:

  1. Create Networking StackSet

aws cloudformation create-stack-set \
  --stack-set-name Networking \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://networking-template.yaml \
  --region us-east-1

2. Create Security StackSet

aws cloudformation create-stack-set \
  --stack-set-name Security \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --template-body file://security-template.yaml \
  --region us-east-1

3. Create Application with dependencies on both Networking and Security

aws cloudformation create-stack-set \
  --stack-set-name Application \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/Networking:uuid,arn:aws:cloudformation:us-east-1:123456789012:Stackset/Security:uuid \
  --template-body file://application-template.yaml \
  --region us-east-1

As a result, Networking and Security StackSets deploy in parallel, and Application waits for both to complete before starting.

Scenario 3: Resolving Dependency Conflicts

Use Case: You need to update existing StackSets to fix incorrect dependency relationships.

Problem: You have App1 and App2 StackSets. There is an existing dependency that App2 has on App1, but you realize App1 should depend on App2, not the other way around.

Implementation:

First, try to set App1 to depend on App2 (this will fail due to cycle):

aws cloudformation update-stack-set \
  --stack-set-name App1 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/App2:uuid \
  --use-previous-template

This action will result in error: “Detected cycle(s) between auto-deployment dependencies”. If dependency validation cannot be completed, you’ll receive appropriate error messages to help troubleshoot configuration issues.

Now let’s remove the existing dependency from App2:

aws cloudformation update-stack-set \
  --stack-set-name App2 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true \
  --use-previous-template

Now successfully set App1 to depend on App2:

aws cloudformation update-stack-set \
  --stack-set-name App1 \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=true,DependsOn=arn:aws:cloudformation:us-east-1:123456789012:StackSet/App2:uuid \
  --use-previous-template

This scenario demonstrates cycle detection and how to resolve dependency conflicts.

Getting Started

StackSet dependencies is available now in all AWS Regions where CloudFormation StackSets are supported. To get started:

  1. Identify Dependencies: Determine which StackSets should deploy first in your infrastructure.
  2. Configure Relationships: Use the CloudFormation console or AWS CLI to set up dependencies using StackSet ARNs.
  3. Test Your Sequence: Validate your dependency configuration in a test environment.
  4. Monitor Deployments: Use CloudFormation events to track sequenced deployments.

Log into your account in the console and visit the AWS CloudFormation StackSets console or use the AWS CLI/SDK with AWS credentials configured to start controlling StackSet dependencies today.

Authors


Tanvi Ravindra Malali

Tanvi Ravindra Malali is an Associate Delivery Consultant in the AWS A2C team in ProServe. She is based in New York City. She handles customer projects and codebases, specializing in AI/ML, Data Engineering and Infrastructure as Code. Outside of work, she loves to paint landscapes, DJing her favorite songs, and dances Tango.

Idriss Louali Abdou
Idriss Laouali Abdou

Idriss Laouali Abdou is a Sr. Product Manager Technical on the AWS Infrastructure-as-Code team based in Seattle. He focuses on improving developer productivity through CloudFormation and StackSets Infrastructure provisioning experiences. Outside of work, you can find him creating educational content for thousands of students, cooking, or dancing.