Tag Archives: AWS Big Data

Streamlined monitoring and debugging for Amazon EMR on EC2

Post Syndicated from Parul Saxena original https://aws.amazon.com/blogs/big-data/streamlined-monitoring-and-debugging-for-amazon-emr-on-ec2/

As organizations scale their data processing and analytics workloads on Amazon EMR on EC2, observability across cluster health, job execution, and resource usage becomes increasingly important. Teams often manage log collection across distributed nodes, correlate Amazon EMR steps with underlying YARN applications, and configure monitoring agents to capture the right level of detail for their environment.

With Amazon EMR release 7.11.0 and updates to the Amazon EMR console, Amazon EMR on EC2 introduces observability capabilities that streamline these workflows further. In this post, we walk you through five key enhancements: Amazon CloudWatch Logs integration, step-level Amazon Simple Storage Service (Amazon S3) logging controls, expanded console UIs for YARN and Tez, Amazon EMR step to YARN application ID mapping, and enhanced custom metrics with updated documentation.

What’s new

The following sections cover key improvements across the Amazon EMR console, logging, metrics collection, and documentation to give you deeper, end-to-end visibility into your Amazon EMR clusters and workloads.

1. CloudWatch Logs integration

Starting with Amazon EMR release 7.11.0, you can stream cluster logs to Amazon CloudWatch Logs in near real time without requiring custom bootstrap actions or manual agent configuration. With Amazon CloudWatch logging enabled, Amazon EMR automatically captures and streams Amazon EMR step execution logs, Spark driver, and Spark executor logs as they’re generated. This makes them immediately available for monitoring, troubleshooting, and post-mortem analysis through the CloudWatch console or API.

You can enable CloudWatch logging through the Amazon EMR console during cluster creation or programmatically using the AWS Command Line Interfaced (AWS CLI) and SDK by including the Amazon CloudWatch Agent in your application configuration and specifying your logging preferences in the configuration section.

With minimal configuration, Amazon EMR captures step logs and Spark driver logs by default, streaming them to a log group named /aws/emr/{cluster_id}. For production workloads requiring stricter organizational and security controls, you can customize the log group name, define a log stream prefix for streamlined filtering, enable encryption with an AWS Key Management Service (AWS KMS) key, and explicitly select which log types to capture. The following example demonstrates a fully customized configuration:

aws emr create-cluster
--name "EMR cluster with custom CloudWatch Logs"
--release-label emr-7.11.0
--applications Name=Spark Name=AmazonCloudWatchAgent
--instance-type m7g.2xlarge
--instance-count 3
--use-default-roles
--monitoring-configuration '
"CloudWatchLogConfiguration":
"Enabled": true,
"LogGroupName": "/my-company/emr/production",
"LogStreamNamePrefix": "cluster-prod",
"EncryptionKeyArn": "arn:aws:kms:us-east-1:123456789012:key/12345678-1234-1234-1234-123456789012",
"LogTypes": {
"STEP_LOGS": ["STDOUT", "STDERR"],
"SPARK_DRIVER": ["STDOUT", "STDERR"],
"SPARK_EXECUTOR": ["STDERR", "STDOUT"]
}
}
}'

This configuration directs the logs to a custom log group (/my-company/emr/production), prefixes log stream names with cluster-prod for consistent identification across clusters, encrypts log data at rest using the specified KMS key, and captures the full set of available log types: step stdout/stderr, Spark driver, and Spark executor output. Because logs are streamed to CloudWatch as they’re written, you have near real-time visibility into job execution without waiting for log aggregation to S3 or establishing direct connectivity to cluster nodes. Combined with CloudWatch Logs Insights, you can run structured querying across log streams, making it straightforward to trace failures, correlate errors across driver and executor logs, and build metric filters or alarms based on specific log patterns.

2. Step-level S3 logging improvements

S3 logging capabilities now provide granular control over how step logs are organized and secured. You can now specify a dedicated S3 log destination and AWS KMS encryption key at the individual Amazon EMR step level. This allows different steps within the same cluster to write logs to separate S3 paths with independent encryption configurations. This is particularly useful for multi-tenant clusters or workflows with varying data classification requirements.

Step-level logging is configured through the StepMonitoringConfiguration parameter, which accepts an S3MonitoringConfiguration object where you can define the target S3 path and an AWS KMS key for encryption at rest:

"StepMonitoringConfiguration": { "S3MonitoringConfiguration": { "LogUri": "s3://your-s3-bucket/", "EncryptionKeyArn": "arn:aws:kms:your-kms-key-arn" } }

This configuration is optional. When omitted, the step inherits the default S3 log path and encryption settings defined at the cluster level during creation. With this configuration, you can override logging behavior only for the steps that require it, while maintaining a consistent default for the rest of your workflow.

3. Enhanced console with direct access to monitoring UIs

Additional live application UIs are accessible directly from the Amazon EMR Console. These console-hosted interfaces remove the need to configure SSH (Secure Shell) tunnels, set up proxies, or establish any direct network connectivity to cluster nodes to reach application web UIs. The newly added interfaces include:

  • YARN ResourceManager UI – Monitor cluster-wide resource allocation, queue usage, and application lifecycle states across running and completed YARN applications. This interface also provides direct access to container-level logs for running YARN applications, enabling real-time debugging without requiring node-level access.
  • Tez UI – Inspect Hive query execution plans, DAG visualizations, vertex-level performance metrics, and task-level counters for queries executed through the Tez execution engine (for example, Hive and Pig workloads).

These join the existing Spark History Server and YARN timeline interfaces already available through the console. By surfacing these UIs, administrators can grant developers and analysts visibility into cluster workloads and application diagnostics without exposing direct network access to cluster infrastructure while maintaining tighter security boundaries and preserving full observability into job execution and resource consumption.

With these additions, Amazon EMR now offers three complementary approaches to accessing application web interfaces, each suited to different operational requirements. Live Application UIs provide console-hosted access to web interfaces on running clusters. They’re recommended for environments where direct network connectivity to cluster nodes must be restricted from end users. On-Cluster Web UIs offer full, unrestricted access to the complete set of native application web interfaces running on cluster nodes, suited for administrators and engineers who require deep, low-level visibility. Persistent Web UIs retain application-level data beyond cluster lifetime, so you can analyze and troubleshoot workloads on terminated clusters. Together, these options give you the flexibility to balance security boundaries, access scope, and data retention based on your team’s specific monitoring and debugging workflows.

4. EMR step to YARN application ID mapping

The Amazon EMR console now surfaces the YARN Application ID directly within the EMR step details panel. For each step executing a Spark, Hive, or other YARN-based workload, the console displays the submitted YARN Application ID associated with that step, establishing a direct link between the EMR step abstraction and the underlying YARN application. With this mapping, you can:

  • Directly correlate EMR steps to YARN applications – when a step fails or exhibits unexpected behavior, you can immediately identify the exact YARN application to investigate rather than manually cross-referencing timestamps or job names across interfaces.
  • Access live monitoring tools – with the YARN application ID readily available, you can navigate directly to the YARN ResourceManager Live UI or the Spark History Server to inspect resource consumption, task-level execution details, and application state for both running and completed jobs.
  • Retrieve logs for detailed troubleshooting – the application ID serves as the key lookup for retrieving container-level logs persisted to Amazon S3, significantly reducing the time to root-cause failures or diagnose performance regressions.

To use this feature, open the Steps tab on your Amazon EMR cluster detail page and select the step that you want to investigate. The YARN Application ID appears in the step details panel. From there, you can use the ID to navigate to the YARN ResourceManager Live UI at http://resourcemanager-host:8088/cluster/app/<application_id>, open the corresponding view in the Spark History Server, or locate the associated container logs in your configured S3 log destination.

5. Enhanced custom metrics and observability documentation

By default, Amazon EMR automatically sends cluster-level metrics to Amazon CloudWatch at five-minute intervals, covering YARN application states, node health, HDFS utilization, and I/O activity. With Amazon EMR Release 7.0 and later, enabling the Amazon CloudWatch Agent extends this baseline with additional detailed metrics collected at one-minute intervals across cluster nodes. Furthermore, Amazon EMR 7.1 introduced custom metric classifications that you can use to define precisely which component-level metrics to collect from Hadoop, YARN, and HBase subsystems, like DataNode I/O activity, NodeManager JVM heap utilization, container resource consumption, and HBase performance counters. Each classification supports configurable export intervals, giving you control over collection granularity based on your monitoring requirements.

After enabled, custom metrics are accessible directly from the Monitoring tab in the Amazon EMR console, where you can use a classification filter to switch between HDFS, YARN, HBase custom metric groupings that you’ve defined. Metric configurations can also be updated on running clusters through the console’s reconfiguration workflow, so you can adapt your monitoring strategy as workload requirements evolve without cluster downtime. For environments using Prometheus, metrics can also be forwarded to Amazon Managed Service for Prometheus and visualized through Grafana dashboards.

The following documentation and tutorials are available to help you get the most out of these capabilities:

Getting started

These observability improvements are available now for Amazon EMR on EC2. To get started:

  1. CloudWatch Logs integration and step-level log configuration: To use these capabilities, launch a new cluster with Amazon EMR release 7.11.0 or later.
  2. For console enhancements: Navigate to your existing Amazon EMR clusters in the AWS Console to access Live Application UI links and YARN Application ID mappings in step details, with no additional configuration required.
  3. For custom metrics: Review our Enhanced Custom Metrics documentation to configure the CloudWatch Agent for publishing Hadoop, YARN, and HBase component metrics using custom classification files.

Conclusion

With these enhancements, Amazon EMR on EC2 provides deeper visibility into cluster health, job execution, and resource usage, helping you reduce time to root cause and focus on delivering value from your data. Note that enabling CloudWatch Logs integration and custom metrics incurs additional CloudWatch charges based on log ingestion volume and metric publishing frequency.

If you have feedback or questions, reach out to your AWS account team or post on the AWS re:Post.


About the authors

Parul Saxena
Parul is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). She helps customers and partners build highly optimized, scalable, and secure solutions. She specializes in Amazon EMR, Amazon Athena, and AWS Lake Formation, providing architectural guidance for complex big data workloads and assisting organizations in modernizing their architectures and migrating analytics workloads to AWS.

Ravi Kumar Singh
Ravi Kumar Singh is a Senior Product Manager Technical-ES (PMT) at Amazon Web Services, specializing in exabyte-scale data infrastructure and analytics platforms. He helps customers unlock insights from their data using open-source technologies and cloud computing for AI/ML use cases. Outside of work, Ravi enjoys exploring emerging trends in data science and machine learning.

Lorenzo Ripani
Lorenzo Ripani is a Big Data Solution Architect at AWS. He is passionate about distributed systems, open-source technologies, and security. He spends most of his time working with customers around the world to design, evaluate and optimize scalable and secure data pipelines with Amazon EMR.

Arun Prabakaran
Arun Prabakaran is a Senior Software Engineer working at AWS. His expertise spans distributed data processing and large-scale systems. He is passionate about building reliable data platforms and enabling organizations to run analytics and AI workloads at scale.

Jason Zou
Jason Zou is a Software Development Engineer at Amazon Web Services, where he works on internal infrastructure supporting EMR clusters. He is passionate about building scalable, fault-tolerant distributed systems. Outside of work, he enjoys photography and playing basketball.

Justin Mae
Justin Mae is a Software Development Engineer on the Amazon EMR team at Amazon Web Services. He works on EMR on EC2’s control plane, building systems that improve cluster performance, observability, and operational reliability.

How to use streamlined permissions for Amazon S3 Tables and Iceberg materialized views

Post Syndicated from Srividya Parthasarathy original https://aws.amazon.com/blogs/big-data/how-to-use-streamlined-permissions-for-amazon-s3-tables-and-iceberg-materialized-views/

Apache Iceberg has emerged as the open table format for data lakes. It handles petabyte-scale datasets, lets teams evolve schemas and partitions in place, and supports time travel and incremental processing for data lake management at scale. Amazon S3 Tables provide a fully managed Apache Iceberg table experience in Amazon S3, optimized for analytics workloads, and integrate with the AWS Glue Data Catalog so AWS analytics services such as Amazon RedshiftAmazon EMRAmazon AthenaAmazon SageMaker, and AWS Glue query your data. Together, they form the foundation of a modern data lake architecture on AWS.

S3 Tables integrate with the AWS Glue Data Catalog using AWS Identity and Access Management (IAM) – based authorization. If you manage analytics workloads across these services, you can now define permissions across storage, catalog, and compute in a single IAM policy. This gives teams already using IAM a straightforward path to govern access to S3 Tables resources without changing their existing permission model. For fine-grained access controls, you can opt in to AWS Lake Formation at any time through the AWS Management Console, AWS Command Line Interface (AWS CLI), API, or AWS CloudFormation.

Iceberg materialized views created in the Glue Data Catalog extend this foundation by letting you store pre-computed query results as Iceberg data on Amazon S3. When a query repeats aggregations or joins across large datasets, the engine reads directly from the materialized view’s S3 location rather than reprocessing the base tables. A materialized view can reside in S3 Tables or in an S3 general purpose bucket, independent of where its base tables live, which lets you place pre-computed results wherever fits your access patterns and cost model best.

In this post, we walk through how to set up and manage S3 Tables in the AWS Glue Data Catalog, create and query Iceberg materialized views, and configure access controls that work across your analytics stack with IAM-based authorization.

 Solution overview

Architecture diagram showing AWS Glue Data Catalog integration with Amazon Athena, AWS Glue, Amazon Redshift, and Amazon EMR through IAM roles and policies, with Amazon S3 storage and optional AWS Lake Formation governance.

The above architecture illustrates how S3 Tables integrate with AWS Glue Data Catalog using IAM-based authorization, so you can define the necessary permissions across storage, catalog, and query engines in a single IAM policy. This permission model accelerates onboarding for new teams and workloads.

Key architecture components include:

Storage Layer: Data stored as Iceberg tables in Amazon S3 Tables

Catalog Layer: AWS Glue Data Catalog serves as the single metadata repository.

Compute Layer – Amazon Athena, AWS Glue, Amazon Redshift, and Amazon EMR connect to a single data Catalog to access Iceberg tables.

Security: AWS IAM authorizes access to resources in storage, catalog, and compute layers.

Prerequisites:

To follow along with this post, you must have an AWS account and an IAM role or user with appropriate permissions and familiarity to the following services:

  • IAM
  • AWS Glue Data Catalog
  • Amazon S3
  • Amazon Athena
  • Amazon Redshift
  • Amazon EMR

For the minimum permissions required for the role/user for metadata and data access, refer to required IAM permissions documentation.

Solution walkthrough

In this walkthrough, you will integrate S3 Tables with the AWS Glue Data Catalog, create Iceberg materialized views, and query data using multiple analytics engines. You will also learn to use materialized views when you have complex aggregations queried frequently but underlying data changes. You can follow these steps to implement the solution. It will take about 45–60 minutes to complete this walkthrough.

Setup S3 Tables and integrate with Glue Data Catalog

Navigate to Amazon S3 console:

  1. On the left menu, select Table buckets.
  2. Choose the Create table bucket button.

Amazon S3 console showing the Table buckets management page in the US West (N. California) us-west-1 Region with zero table buckets, integration status disabled, and the Create table bucket button highlighted.

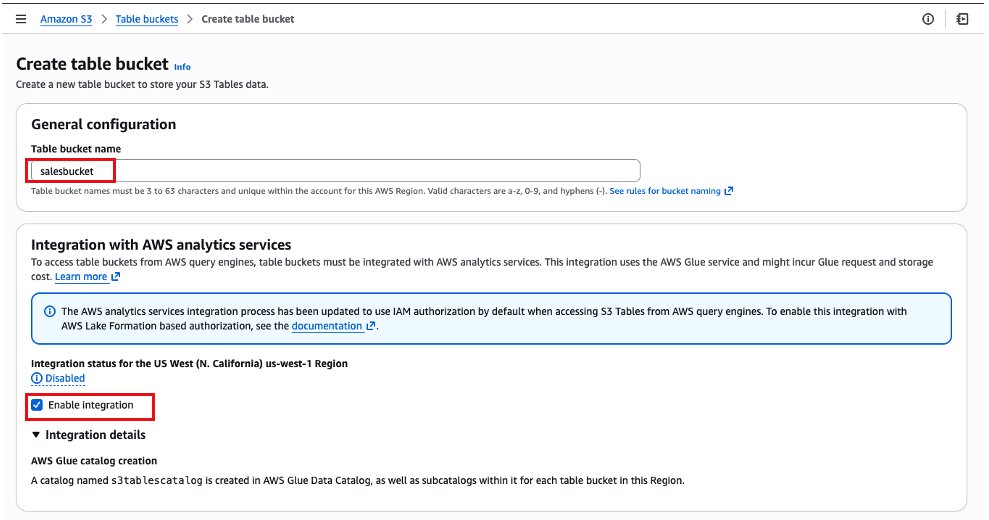
  1. In the next screen, we will fill the name of the bucket as salesbucket. Please ensure the Enable Integration configuration is checked. This step integrates S3 Tables with AWS Glue Data Catalog.

AWS S3 Create table bucket form with General configuration showing bucket name "salesbucket" and Integration with AWS analytics services section with Enable integration checkbox selected.

  1. Keep the other options as default and choose Create table bucket.
  2. After it is created, you will be redirected back to the list of table buckets. Choose the table bucket salesbucket.
  3. Select the Create table with Athena button.
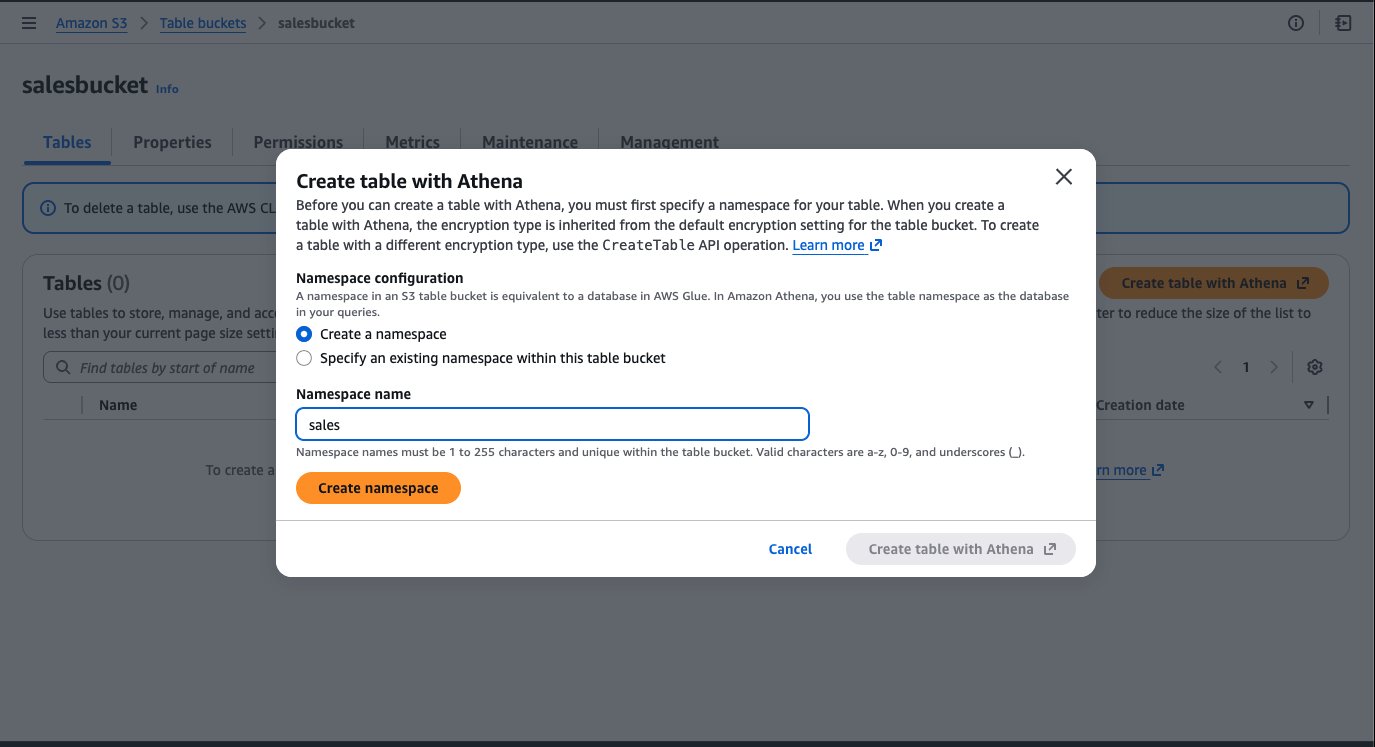
  4. Create a namespace in S3 Tables which is equivalent to a database in AWS Glue Data Catalog. Enter namespace (database) name as “sales” and click Create namespace.

Create table with Athena dialog in the Amazon S3 salesbucket console showing namespace configuration with "Create a namespace" selected and namespace name set to "sales."

  1. Choose Create table with Athena, and a new tab will be open with the Amazon Athena console.
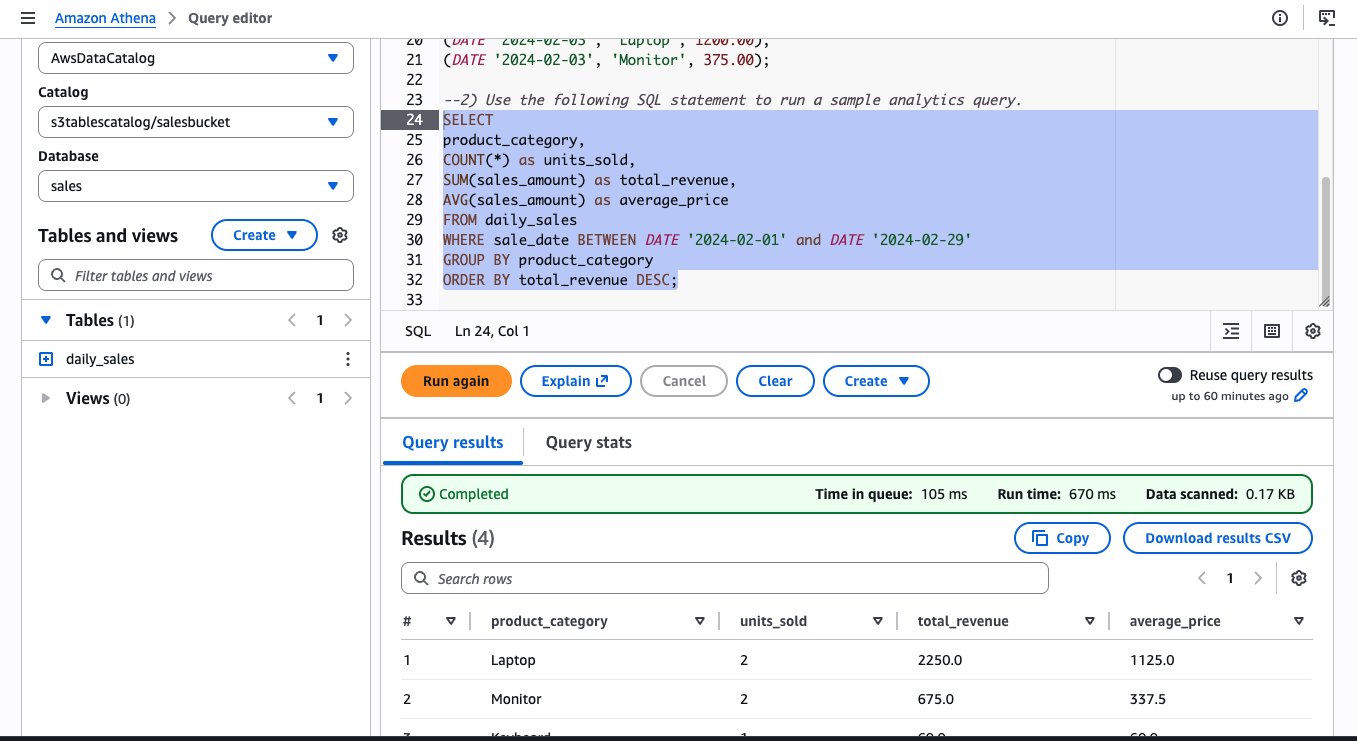
  2. When the Amazon Athena console opens, you will see an example of a query to create a table and examples to insert rows in that table. You could use this query block by uncommenting the code and executing each statement individually by highlighting it. At the end, you will have data in the table.

Amazon Athena query editor showing a SQL analytics query on the daily_sales table with results displaying product categories, units sold, total revenue, and average price for February 2024 sales data.

Query S3 Tables and create materialized view using Amazon EMR:

To run the instruction on Amazon EMR, complete the following steps to configure the cluster:

  1. Create an IAM role for the Amazon EMR instance profile following the Amazon EMR Management Guide. Add the following as policies and trust relationship for working on materialized views.

Replace ACCOUNT_ID with your AWS account ID, Instance_profile_role to the Amazon EMR instance profile role, and REGION with your AWS Region.

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"GlueDataCatalogPermissions",
         "Effect":"Allow",
         "Action":[
            "glue:GetCatalog",
            "glue:GetDatabase",
            "glue:CreateTable",
            "glue:GetTable",
            "glue:GetTables",
            "glue:UpdateTable",
            "glue:DeleteTable"
         ],
         "Resource":[
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/salesdb",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/salesdb/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:table/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:table/*/*"
         ]
      },
      {
         "Sid":"S3TablesDataAccessPermissions",
         "Effect":"Allow",
         "Action":[
            "s3tables:GetTableBucket",
            "s3tables:GetNamespace",
            "s3tables:GetTable",
            "s3tables:GetTableMetadataLocation",
            "s3tables:GetTableData",
            "s3tables:ListTableBuckets",
            "s3tables:CreateTable",
            "s3tables:PutTableData",
            "s3tables:UpdateTableMetadataLocation",
            "s3tables:ListNamespaces",
            "s3tables:ListTables",
            "s3tables:DeleteTable"
         ],
         "Resource":[
            "arn:aws:s3tables:<REGION>:<ACCOUNT ID>:bucket/*"
         ]
      },
      {
         "Effect":"Allow",
         "Action":"iam:PassRole",
         "Resource":"arn:aws:iam::<ACCOUNT ID>:role/service-role/<Instance_profile_role>"
      }
   ]
}

Add the following to the trust policy in addition to existing:

 {
            "Sid": "",
            "Effect": "Allow",
            "Principal": {
                "Service": "glue.amazonaws.com"
            },
            "Action": "sts:AssumeRole"
        }
  1. Launch an Amazon EMR cluster 7.12.0 or higher with instance profile role created in the previous step and with Iceberg enabled. For more information, refer to Use an Iceberg cluster with Spark.
  2. Connect to the primary node of your Amazon EMR cluster by using SSH, and run the following command to start a Spark application with the required configurations:

Replace bucket_name with your bucket name.

spark-sql \
  --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
  --conf spark.sql.catalog.glue_catalog=org.apache.iceberg.spark.SparkCatalog \
  --conf spark.sql.catalog.glue_catalog.type=glue \
  --conf spark.sql.catalog.glue_catalog.warehouse=s3://<bucket_name> \
  --conf spark.sql.catalog.glue_catalog.glue.region=<region> \
  --conf spark.sql.catalog.glue_catalog.glue.id=<accountid>:s3tablescatalog/salesbucket \
  --conf spark.sql.catalog.glue_catalog.glue.account-id=<accountid> \
  --conf spark.sql.catalog.glue_catalog.client.region=<region> \
  --conf spark.sql.optimizer.answerQueriesWithMVs.enabled=true \
  --conf spark.sql.defaultCatalog=glue_catalog
  1. Run the following queries to query the daily_sales table.
spark-sql ()> use sales;
spark-sql (sales)> select * from daily_sales;
2024-01-15 Laptop 900.0
2024-01-15 Monitor 250.0
2024-01-16 Laptop 1350.0
2024-02-01 Monitor 300.0
2024-02-01 Keyboard 60.0
2024-02-02 Mouse 25.0
2024-02-02 Laptop 1050.0
2024-02-03 Laptop 1200.0
2024-02-03 Monitor 375.0
  1. Create Materialized view.
CREATE MATERIALIZED VIEW sales_mv as 
SELECT 
    product_category,
    COUNT(*) as units_sold,
    SUM(sales_amount) as total_revenue, 
    AVG(sales_amount) as average_price 
FROM 
    glue_catalog.sales.daily_sales 
GROUP BY 
    product_category;

A newly created materialized view is populated with the initial query results but does not update automatically as base table data changes. To keep it current, specify a REFRESH EVERY clause when creating the view. This accepts a time interval and unit, so you can define how often the materialized view is recomputed from the base tables.

  1. Add refresh interval.
CREATE MATERIALIZED VIEW sales_mv 
SCHEDULE REFRESH EVERY 2 HOURS as 
SELECT 
    product_category,
    COUNT(*) as units_sold,
    SUM(sales_amount) as total_revenue, 
    AVG(sales_amount) as average_price 
FROM 
    glue_catalog.sales.daily_sales 
GROUP BY 
    product_category;
  1. Alternatively, you can refresh them manually.

For manual full refresh, you can use the following command:

REFRESH MATERIALIZED VIEW sales_mv FULL;

For manual incremental refresh, you can use the following command:

REFRESH MATERIALIZED VIEW sales_mv;

For more details, refer to Refreshing materialized views.

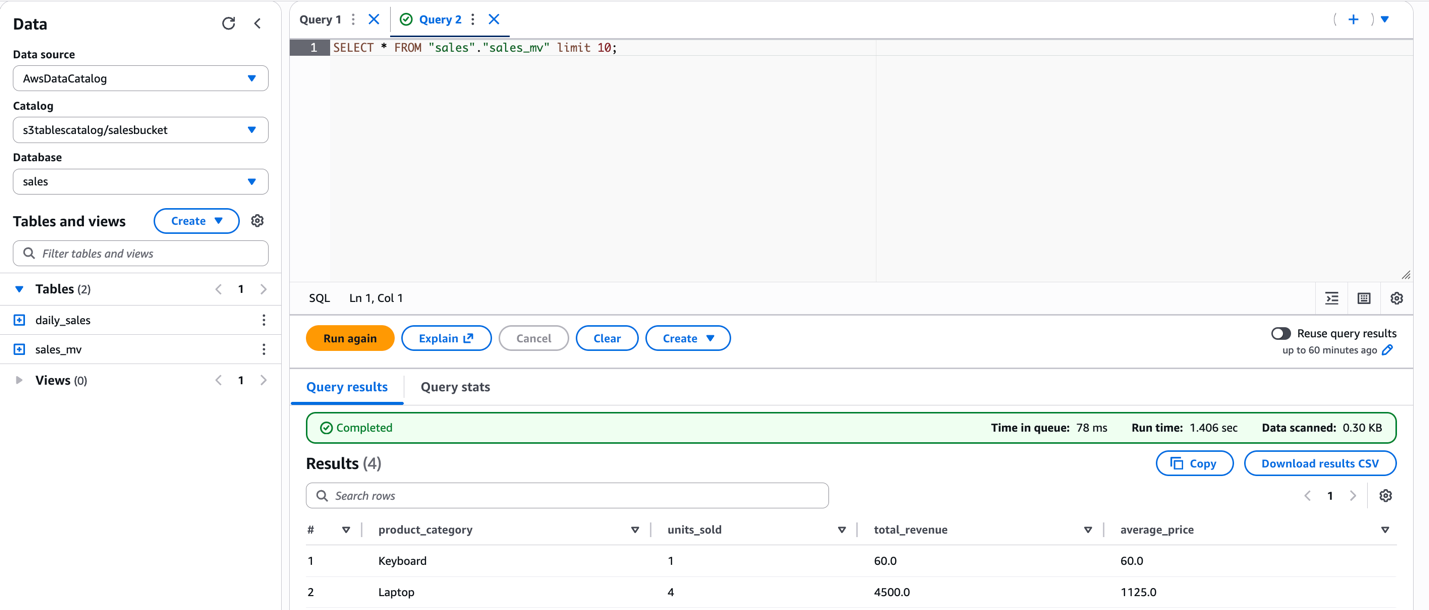
  1. Query the MV.
spark-sql (sales)> select * from sales_mv
Keyboard 1 60.0 60.0
Laptop 4 4500.0 1125.0
Mouse 1 25.0 25.0
Monitor 3 925.0 308.3333333333333

After the Iceberg materialized views are created, you can access them using IAM principals that have required IAM permissions to Glue Data Catalog resource and its underlying storage.

Iceberg materialized views are flexible in how they combine base tables and access control modes. Base tables can reside in S3 general-purpose buckets (with IAM or Lake Formation access control), in S3 Tables (through the s3tablescatalog catalog), or a combination of these—all within a single materialized view definition. The materialized view itself can use either IAM or AWS Lake Formation access control, independently of its base tables.

For more details, refer to How materialized views work with AWS Glue.

Query using Athena:

Additionally, you can query the same materialized view from Athena SQL. The following image shows the same query run on Athena and the resulting output.Amazon Athena query editor showing SELECT query results from the sales_mv materialized view with product category aggregations including Keyboard and Laptop sales data.

Query using Amazon Redshift:

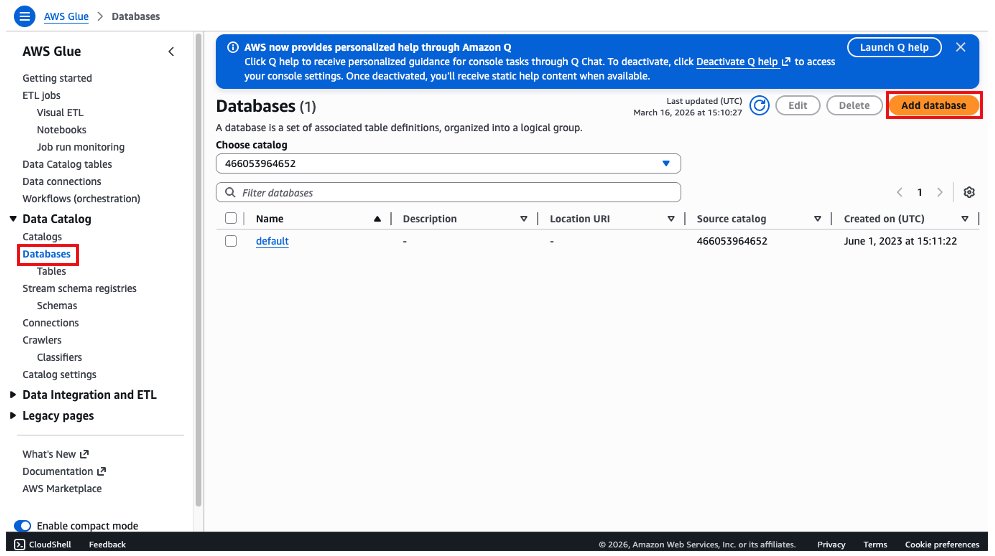
To query the S3 Tables in AWS Glue Data Catalog using Amazon Redshift, you must create a database in the default catalog in Glue Data Catalog that points to the S3 Tables catalog.

  1. On the AWS Glue console, choose Databases, and then choose Add Database.

AWS Glue Data Catalog Databases page showing one default database in catalog 466053964652, with the Add database button highlighted.

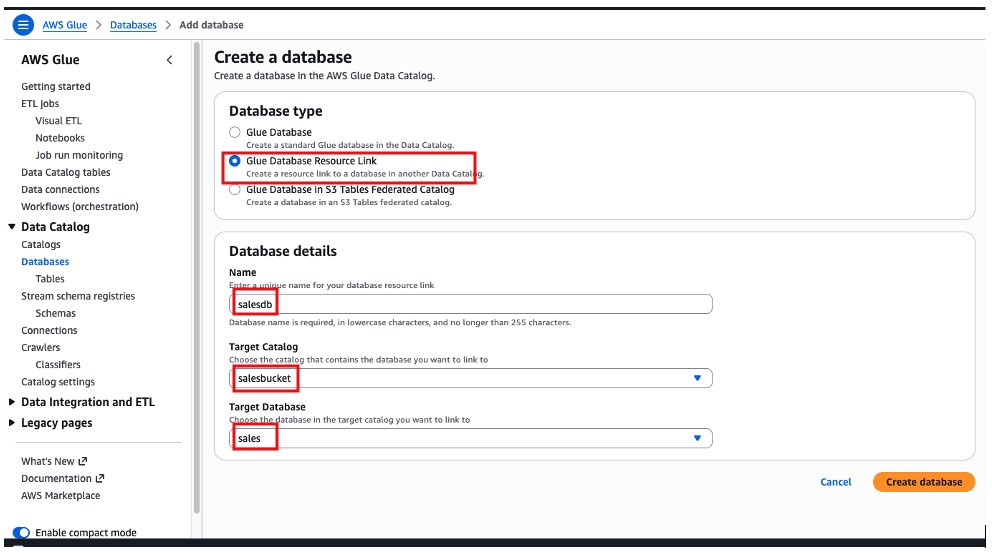
  1. Choose the Glue Database resource link option, add a name for the database, choose salesbucket on the target catalog and sales as the target database. Then select Create database.

AWS Glue Create a database form with Glue Database Resource Link selected, name set to "salesdb," target catalog "salesbucket," and target database "sales."

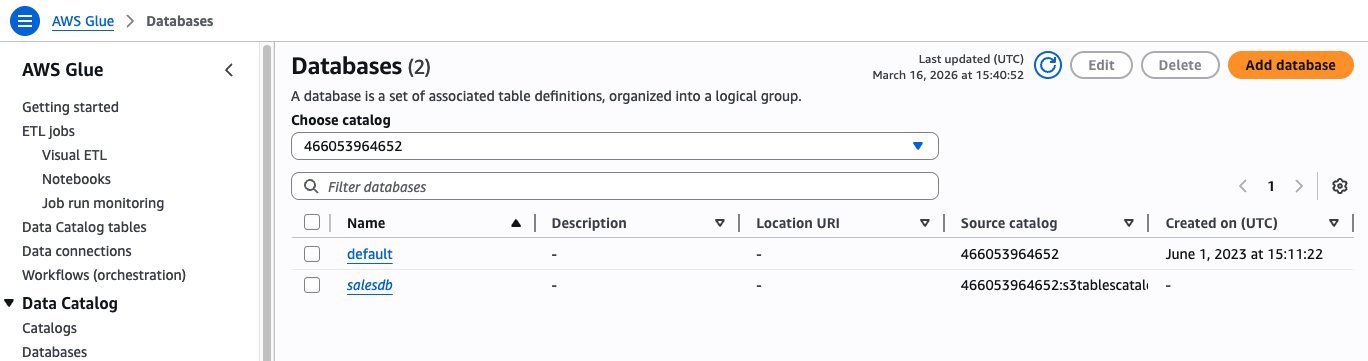
After creating the database, we will see the “salesdb” resource link under Databases on AWS Glue Data Catalog.

AWS Glue Data Catalog Databases page showing two databases: "default" and the newly created "salesdb" resource link with source catalog pointing to s3tablescatalog.

Create IAM role with the following policy for the Amazon Redshift schema creation. Replace the AWS Region and account ID for your account.

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"GlueDataCatalogPermissions",
         "Effect":"Allow",
         "Action":[
            "glue:GetCatalog",
            "glue:GetDatabase",
            "glue:CreateTable",
            "glue:GetTable",
            "glue:GetTables",
            "glue:UpdateTable",
            "glue:DeleteTable"
         ],
         "Resource":[
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/salesdb",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/salesdb/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:table/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:table/*/*"
         ]
      },
      {
         "Sid":"S3TablesDataAccessPermissions",
         "Effect":"Allow",
         "Action":[
            "s3tables:GetTableBucket",
            "s3tables:GetNamespace",
            "s3tables:GetTable",
            "s3tables:GetTableMetadataLocation",
            "s3tables:GetTableData",
            "s3tables:ListTableBuckets",
            "s3tables:CreateTable",
            "s3tables:PutTableData",
            "s3tables:UpdateTableMetadataLocation",
            "s3tables:ListNamespaces",
            "s3tables:ListTables",
            "s3tables:DeleteTable"
         ],
         "Resource":[
            "arn:aws:s3tables:<REGION>:<ACCOUNTID>:bucket/*"
         ]
      }
   ]
}

Create an Amazon Redshift provisioned cluster or Amazon Redshift Serverless, attaching the IAM role created in previous step.

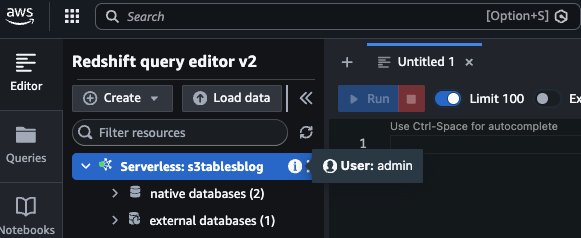
To access the AWS Glue Catalog and the resource link, you can now log in to Amazon Redshift as a local user. We use the admin user and Amazon Redshift Query Editor v2.

Amazon Redshift Query Editor v2 interface connected to Serverless workgroup "s3tablesblog" showing 2 native databases and 1 external database with an empty query editor ready for input.

To create the external schema, you must run the following command: Replace ACCOUNT_ID with your AWS Account ID, IAM_ROLE to IAM role created for schema access, and REGION with your AWS Region.

CREATE EXTERNAL SCHEMA salesdb
FROM DATA CATALOG DATABASE 'salesdb'
IAM_ROLE 'arn:aws:iam::<ACCOUNT_ID>:role/<IAM_ROLE>'
REGION '<REGION>'
CATALOG_ID '<ACCOUNT_ID>';

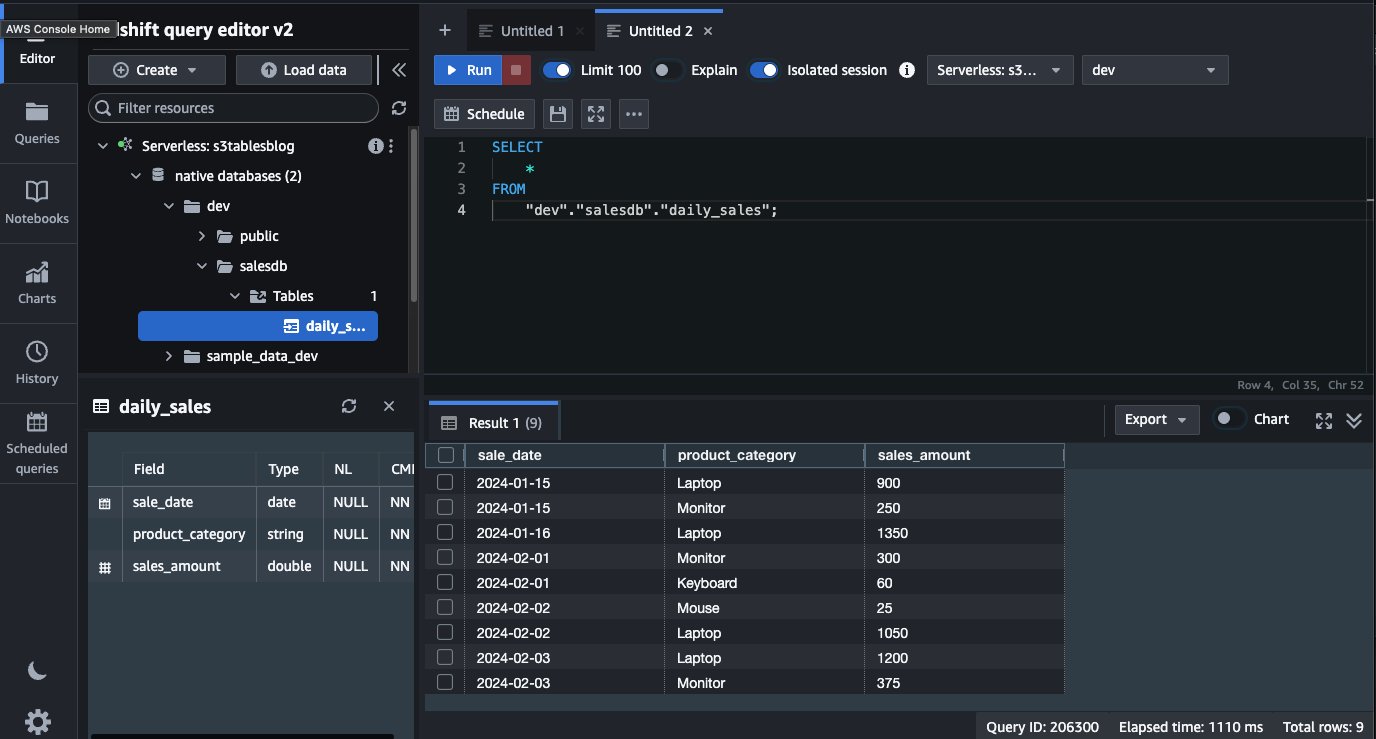
After you have created the external schema, it will show up on the left side, under the dev database. The table that we created, daily_sales, is available and we can query directly from Amazon Redshift using a local user.

Amazon Redshift Query Editor v2 showing a SELECT query on the daily_sales table in the salesdb schema with 9 rows of results displaying sale dates, product categories, and sales amounts from January–February 2024.

Cleanup:

After completing the walkthrough, follow these steps to remove the resources and avoid ongoing charges. These cleanup steps will permanently delete the data, including the daily_sales table and sales_mv materialized view. Make sure that you have backed up the data that you need to retain before proceeding.

To avoid incurring future charges, clean up the resources that you created during this walkthrough:

  • Remove the Glue Data Catalog resources
  • Delete the table bucket
  • Terminate and Delete the Amazon Redshift cluster
  • Terminate and Delete the Amazon EMR cluster
  • Delete the IAM roles/policies created

Conclusion

Amazon S3 Tables now integrate with AWS Glue Data Catalog through IAM-based authorization via a single IAM policy. By consolidating permissions for storage, catalog, and query engines into one IAM policy, you can streamline authorization with AWS analytics services like Amazon Athena, Amazon EMR, and AWS Glue. You can use this streamlined IAM authorization model to build your data lake faster while maintaining enterprise-grade security. For organizations with additionally granular data access requirements, AWS Lake Formation remains available to layer fine-grained access controls on top of this foundation. This is configurable through the AWS Management Console, CLI, API, or CloudFormation. This integration allows AWS analytics users to use IAM and scale their analytics capabilities with reduced operational complexity.

To learn more about to S3 Tables and integration with Glue Data catalog, visit: Amazon S3 Tables integration with AWS analytics services overview and Integrating with Amazon S3 Tables.


About the authors

Ricardo Serafim

Ricardo is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.

Milind Oke

Milind is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.

Pratik Das

Pratik is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems.

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Building unified data pipelines with Apache Iceberg and Apache Flink

Post Syndicated from Nikhil Jha original https://aws.amazon.com/blogs/big-data/building-unified-data-pipelines-with-apache-iceberg-and-apache-flink/

You can process real-time data from your data lake with Amazon Managed Service for Apache Flink without maintaining two separate pipelines. Yet many teams do exactly that, and the cost adds up fast. In this post, you build a unified pipeline using Apache Iceberg and Amazon Managed Service for Apache Flink that replaces the dual-pipeline approach. This walkthrough is for intermediate AWS users who are comfortable with Amazon Simple Storage Service (Amazon S3) and AWS Glue Data Catalog but new to streaming from Apache Iceberg tables.

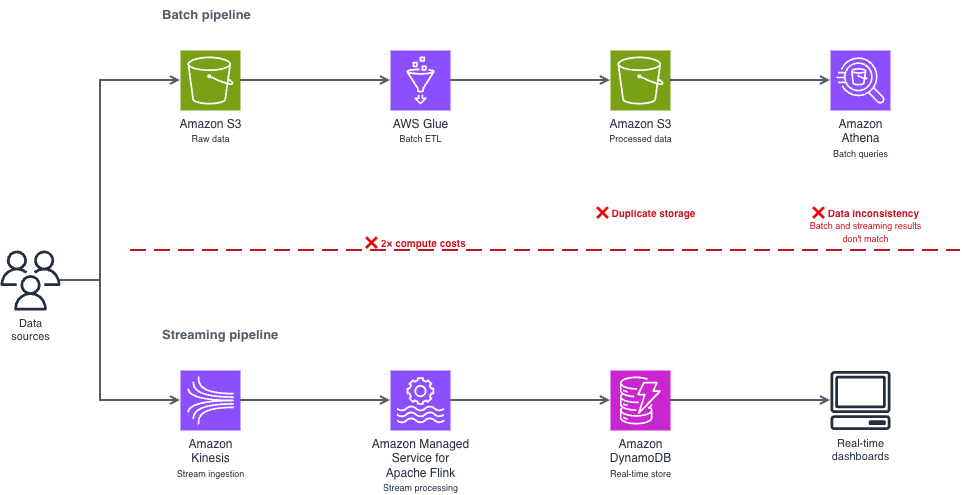
The dual-pipeline problem

Traditional dual-pipeline architecture with separate batch and streaming paths, each with its own ingestion, processing, storage, and serving layers, processing the same source data independently.

This dual-pipeline approach creates three problems:

  • Double the infrastructure costs. You run and pay for two separate compute environments, two storage layers, and two sets of monitoring. For example, if you’re spending $10,000/month on separate streaming and batch infrastructure, a meaningful portion of that spend is pure duplication.
  • Data synchronization issues. Your batch and streaming consumers read from different copies of the data, processed at different times. When a transaction shows up in your real-time dashboard but not in your batch report (or vice versa), debugging the inconsistency takes hours.
  • Operational complexity. Two pipelines mean two deployment processes, two failure modes to monitor, and two sets of schema evolution to manage. Your team spends time reconciling systems instead of building features.

Where this pattern fits

Before diving into the implementation, consider whether streaming from your data lake is the right approach for your use case.

Streaming from Apache Iceberg tables works well when you need data available within seconds to minutes and you query recent data frequently, multiple times per hour. Common scenarios include:

  • Operational data stores — Stream customer profile updates to serve downstream applications like recommendation engines. When a customer updates their preferences, those changes reach your operational data store within seconds.
  • Fraud detection — Stream transactions for immediate analysis. Start with a 3-second monitor interval and adjust based on your detection accuracy needs.
  • Live dashboards — Power real-time analytics directly from your lake. This is the strongest starting point if you’re evaluating the approach for the first time, because the feedback loop is immediate and straightforward to validate.
  • Event-driven architectures — Trigger downstream processes based on data changes in your Apache Iceberg tables.

Batch processing remains more cost-effective when you process data once per day or less, or you primarily query historical data. Batch queries on Apache Iceberg tables cost less because they don’t require a continuous Apache Flink runtime.

How Apache Iceberg solves this

Apache Iceberg’s snapshot-based architecture removes the need for a separate streaming pipeline. Think of snapshots like Git commits for your data. Each time you write data to your Iceberg table, Iceberg creates a new snapshot that points to the new data files while preserving references to existing files. Apache Flink reads only the changes between snapshots (the new files that arrived after the last checkpoint), rather than scanning the entire table. Atomicity, Consistency, Isolation, Durability (ACID) transactions prevent your concurrent reads and writes from producing partial or inconsistent results. For example, if your batch extract, transform, and load (ETL) job is writing 10,000 records while your Flink application is reading, ACID transactions mean that your streaming query sees either the complete batch of 10,000 records or none of them, not a partial set that could skew your analytics.

The result is a single pipeline that handles both real-time and batch access from the same data, through the same storage layer, with the same schema.

Solution architecture

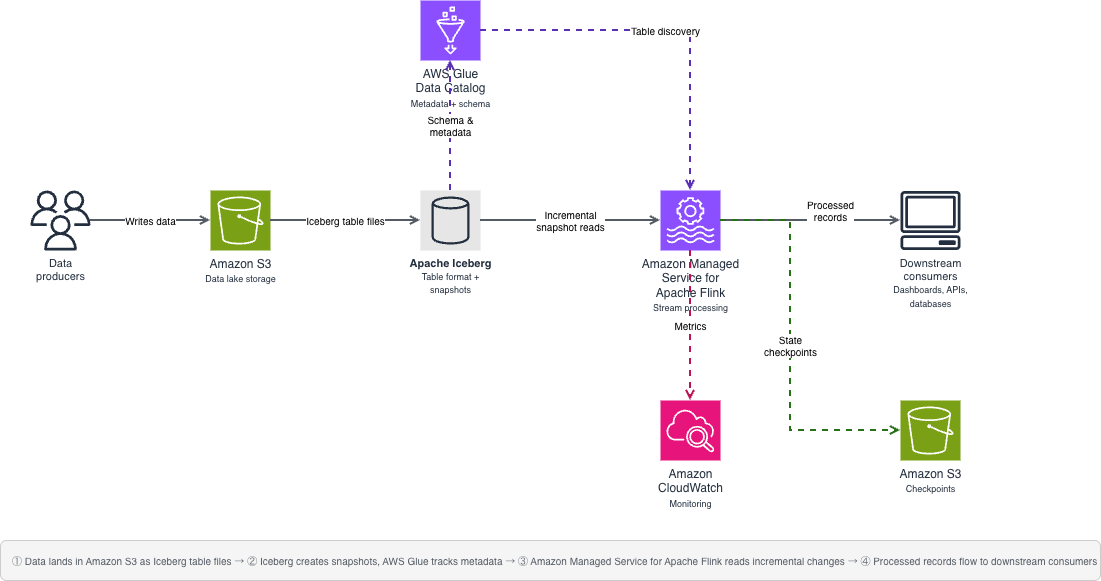
Your architecture uses four AWS services and one open source table format working together. The following diagram shows how these components connect, replacing the dual-pipeline pattern shown earlier with a single unified flow.

Unified pipeline architecture with data flowing from Amazon S3 through Apache Iceberg tables, with AWS Glue Data Catalog managing metadata, and Amazon Managed Service for Apache Flink consuming incremental snapshots for near real-time processing.

Your source data lands in Amazon S3 as Apache Iceberg table files. AWS Glue Data Catalog tracks the metadata and schema. When new data arrives, Apache Iceberg creates a new snapshot that your application detects. Your Flink application monitors these snapshots and processes new records incrementally, reading only the files that arrived after the last checkpoint, not the entire table.

You use four main components:

  • Amazon S3 — Foundational storage layer for your data lake
  • Data Catalog — Metadata and schema management for Apache Iceberg tables
  • Apache Iceberg — Table format with snapshot-based streaming capabilities
  • Amazon Managed Service for Apache Flink — Stream processing and incremental consumption

Important notices

Before implementing this solution, evaluate these risks for your environment:

  • Data security: Streaming from data lakes exposes data to additional processing systems. Classify your data before implementation—customer profile updates and transaction data typically contain personally identifiable information (PII) and treat them as confidential. Apply encryption at rest and in transit for confidential data. Key risks include unauthorized data access through misconfigured Amazon S3 bucket policies or overly permissive IAM roles. Mitigations: use the resource-scoped IAM policy and TLS-enforcing bucket policy provided in the Security section.
  • Data integrity: Misconfigured checkpoints or schema changes during streaming can lead to data inconsistency. Mitigations: enable exactly-once processing semantics and test schema evolution in a non-production environment first.
  • Compliance: Verify that real-time data processing meets your regulatory requirements. For workloads subject to HIPAA, confirm that you use HIPAA Eligible Services and have a Business Associate Agreement (BAA) with AWS. For PCI-DSS or GDPR workloads, review the relevant compliance documentation on the AWS Compliance page. Implement data retention policies that comply with your regulatory framework.
  • Cost: Nearly continuous streaming incurs ongoing compute costs. Monitor usage to avoid unexpected charges. Cost estimates in this post are based on pricing as of March 2026 and might change. Verify current pricing on the relevant AWS service pricing pages.
  • Operational: Pipeline failures might impact downstream systems. Implement monitoring and alerting before running in production.

Prerequisites

Before you begin, make sure that you have the following in place. This walkthrough assumes intermediate Python skills (comfortable with functions, error handling, and environment variables), basic Apache Flink concepts (streaming compared to batch processing), and basic AWS Identity and Access Management (AWS IAM) knowledge (creating roles and attaching policies). Plan for approximately 90–120 minutes, including setup, implementation, and testing. First-time setup might take longer as you download dependencies and configure AWS resources. Expected AWS costs: approximately $5–10 if you complete the walkthrough within 2 hours and clean up resources immediately afterward. The primary cost driver is Amazon Managed Service for Apache Flink runtime ($0.11/hour per Kinesis Processing Unit (KPU)). You can minimize costs by stopping your application when not in use.

  • An AWS account with AWS IAM permissions for: s3:GetObject, s3:PutObject, s3:ListBucket on your data bucket; glue:GetDatabase, glue:GetTable for catalog access; and flink:CreateApplication, flink:StartApplication for Amazon Managed Service for Apache Flink
  • An existing Amazon S3 bucket for your data lake
  • An AWS Glue Data Catalog database configured
  • Apache Flink 1.19.1 installed locally
  • Python 3.8 or later
  • Java 11 or a more recent version
  • AWS Command Line Interface (AWS CLI) configured with credentials (aws configure)

Required Java Archive (JAR) dependencies

You need multiple JAR files because your Flink application coordinates between different systems—Amazon S3 for storage, AWS Glue for metadata, Hadoop for file operations, and Apache Iceberg for the table format. Each JAR handles a specific part of this integration. Missing even one causes ClassNotFoundException errors at runtime.

  • iceberg-flink-runtime-1.19-1.6.1.jar — Core Apache Iceberg integration with Apache Flink
  • iceberg-aws-bundle-1.6.1.jar — AWS-specific Apache Iceberg functionality for Amazon S3 and AWS Glue
  • flink-s3-fs-hadoop-1.19.1.jar — Provides Apache Flink read and write access to Amazon S3
  • flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar — Hive metastore connector for catalog compatibility
  • hadoop-common-3.4.0.jar — Core Hadoop libraries required by Apache Iceberg
  • flink-shaded-hadoop-2-uber-2.8.3-10.0.jar — Repackaged Hadoop dependencies that avoid version conflicts with Apache Flink
  • hadoop-hdfs-client-3.4.0.jar — Hadoop Distributed File System (HDFS) client libraries for file system operations
  • flink-json-1.19.1.jar — JSON format support for Apache Flink
  • hadoop-aws-3.4.0.jar — Hadoop integration with AWS services
  • hadoop-client-3.4.0.jar — Hadoop client libraries
  • aws-java-sdk-bundle-1.12.261.jar — AWS SDK for authentication and service access
jars = [
    "flink-s3-fs-hadoop-1.19.1.jar",
    "flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar",
    "hadoop-common-3.4.0.jar",
    "flink-shaded-hadoop-2-uber-2.8.3-10.0.jar",
    "iceberg-flink-runtime-1.19-1.6.1.jar",
    "iceberg-aws-bundle-1.6.1.jar",
    "hadoop-hdfs-client-3.4.0.jar",
    "flink-json-1.19.1.jar",
    "hadoop-aws-3.4.0.jar",
    "hadoop-client-3.4.0.jar",
    "aws-java-sdk-bundle-1.12.261.jar"
]

Technical implementation

The sample code in this post is available under the MIT-0 license.This section walks you through building the streaming pipeline step by step. You create a single Python file, iceberg_streaming.py, with three functions that run in sequence. Your main() function calls them in order: set up the Apache Flink environment, register the Data Catalog, then start the streaming query.

Set up your Apache Flink environment

To prepare your Apache Flink environment:

  1. Download the required JAR files listed in the prerequisites section.
  2. Place the JAR files in a lib directory in your project folder.
  3. Configure your HADOOP_CLASSPATH environment variable to point to the lib directory.
  4. Create your streaming execution environment by adding the following function to iceberg_streaming.py:
def setup_environment():
    """Configure the Flink streaming runtime."""
    try:
        os.environ['HADOOP_CLASSPATH'] = os.path.join(os.getcwd(), 'lib', '*')
        env = StreamExecutionEnvironment.get_execution_environment()
        env.set_parallelism(1)
        settings = EnvironmentSettings.new_instance().in_streaming_mode().build()
        t_env = StreamTableEnvironment.create(env, settings)
        return t_env
    except Exception as e:
        print(f"Failed to initialize Flink environment: {e}")
        raise
  1. Verify your environment by running flink –version. If the command isn’t found, confirm that Apache Flink 1.19.1 is installed and that your PATH includes the Flink bin directory.

Configure AWS Glue Data Catalog

To connect your Flink application to Data Catalog:

  1. Open your iceberg_streaming.py file.
  2. Add the create_iceberg_source() function shown in the following section.
  3. Replace the placeholder values with your actual AWS resources before running. These values are static configuration strings, not user input — do not construct them from external or untrusted sources at runtime.
  4. Save the file.
def create_iceberg_source(t_env):
    """Register the AWS Glue Data Catalog as an Iceberg catalog."""
    try:
        catalog_sql = """
        CREATE CATALOG glue_catalog WITH (
            'type'='iceberg',
            'catalog-impl'='org.apache.iceberg.aws.glue.GlueCatalog',
            'warehouse'='s3://<example-data-lake-bucket>',
            'io-impl'='org.apache.iceberg.aws.s3.S3FileIO',
            'aws.region'='us-east-1',
            'hadoop-conf.fs.s3a.aws.credentials.provider'=
                'com.amazonaws.auth.DefaultAWSCredentialsProviderChain',
            'hadoop-conf.fs.s3a.endpoint'='s3.amazonaws.com',
            'property-version'='1'
        )
        """
        t_env.execute_sql(catalog_sql)
        t_env.use_catalog("glue_catalog")
        t_env.use_database("streaming_db")
    except Exception as e:
        print(f"Failed to configure Iceberg catalog: {e}")
        raise

Set up streaming logic

This function configures Apache Flink to monitor your Apache Iceberg table continuously and process new records as they arrive. Checkpointing runs every 10 seconds to track progress—if the job restarts, it resumes from the last checkpoint rather than reprocessing the entire table.Notice the monitor-interval parameter, it controls how frequently Apache Flink checks for new Apache Iceberg snapshots. A 3-second interval provides near real-time processing but generates approximately 1,200 Amazon S3 LIST API calls per hour (at $0.005 per 1,000 requests, roughly $0.04/month per table based on pricing as of March 2026). For less time-sensitive workloads, increase this to 30s to reduce API costs by 90%.Replace customer_events with the name of your Apache Iceberg table in Data Catalog:

def process_record(row):
    """Validate and process each record from the stream."""
    try:
        if row is None:
            raise ValueError("Received null row")
        required_fields = ["event_type", "timestamp"]
        for field in required_fields:
            if field not in row:
                raise ValueError(f"Missing required field: {field}")
        # Validate field types and content
        if not isinstance(row.get("event_type"), str) or len(row["event_type"]) > 256:
            raise ValueError("event_type must be a string under 256 characters")
        if not isinstance(row.get("timestamp"), (str, int)):
            raise ValueError("timestamp must be a string or integer")
        # Replace with your business logic
        print(f"Processing record: {row}")
    except ValueError as e:
        print(f"Validation error for record {row}: {e}")
    except Exception as e:
        print(f"Error processing record {row}: {e}")
def stream_data(t_env):
    """Start the streaming query and process results."""
    try:
        configuration = t_env.get_config().get_configuration()
        configuration.set_string("table.dynamic-table-options.enabled", "true")
        configuration.set_string("execution.checkpointing.interval", "10000")
        query = """
        SELECT * FROM customer_events /*+ OPTIONS(
            'streaming'='true',
            'monitor-interval'='3s',
            'table.exec.iceberg.cell-based-snapshot'='true'
        ) */
        """
        table_result = t_env.execute_sql(query)
        with table_result.collect() as results:
            for row in results:
                process_record(row)
    except Exception as e:
        print(f"Streaming query failed: {e}")
        raise

Putting it together

Your main() function calls the three steps in order:

def main():
    try:
        t_env = setup_environment()
        create_iceberg_source(t_env)
        stream_data(t_env)
    except Exception as e:
        print(f"Pipeline failed: {e}")
        raise
if __name__ == "__main__":
    main()

Run the pipeline locally:python iceberg_streaming.pyPackage the application and submit it to Amazon Managed Service for Apache Flink using the console or the AWS Command Line Interface (AWS CLI).

Running in production

Moving from a local test to a production deployment requires tuning four areas: performance, monitoring, cost, and security. This section covers the key decisions for each.

Performance tuning

Determine your latency requirements before tuning. For fraud detection, you need subsecond processing. For daily reporting dashboards, you can tolerate minutes of delay.

Partition pruning reduces the amount of data scanned per query. Proper partitioning can significantly reduce query times for time series data partitioned by date. To implement, create your Apache Iceberg table with partition columns (PARTITIONED BY (date_column) in your CREATE TABLE statement), then include partition filters in your WHERE clause: WHERE date_column >= CURRENT_DATE - INTERVAL '7' DAY.

Parallel processing matches your data volume and throughput requirements. For most workloads under 10,000 records per second, a parallelism of 1–4 is sufficient. Scale up incrementally and monitor backpressure metrics (indicators that data arrives faster than your pipeline processes it, causing queuing) to find the right setting.

Checkpoint tuning balances reliability and latency. Consider how much data you can afford to reprocess after a failure. If you process 1,000 records per second with 10-second checkpoints, a failure means reprocessing up to 10,000 records. When that’s acceptable, 10 seconds works well. For faster recovery or higher volumes, reduce to 5 seconds.

Resource allocation — Right-size your Apache Flink cluster to avoid over-provisioning. Monitor CPU and memory utilization during your initial runs and adjust task manager resources accordingly.

Monitoring

Configure your production deployment with the following checkpoint settings. These work well for moderate data volumes (up to 10,000 records per second), providing exactly-once processing semantics. This means that the pipeline processes each record exactly once, even if your application restarts. Adjust the checkpoint interval based on your latency requirements. Add this to your setup_environment() function after creating the table environment.

config_dict = {
    "execution.checkpointing.interval": "30000",
    "execution.checkpointing.mode": "EXACTLY_ONCE",
    "execution.checkpointing.timeout": "600000",
    "state.backend": "filesystem",
    "state.checkpoints.dir": "s3://<example-data-lake-bucket>/checkpoints"
}

Use Amazon CloudWatch to track checkpoint duration, records processed per second, and backpressure metrics. A 10-second checkpoint interval means writing state to Amazon S3 360 times per hour. For a 1 MB state size, that’s approximately 8.6 GB per day in checkpoint storage—at Amazon S3 Standard pricing of $0.023/GB, roughly $0.20/day or $6/month per application based on current pricing. If the checkpoint duration exceeds 50% of your interval, increase the interval or add parallelism.

Cost management

Use Amazon S3 Intelligent-Tiering for your Apache Iceberg data files, which typically have predictable access patterns after initial processing. Configure Apache Iceberg’s table expiration to automatically clean up early snapshots. This can reduce storage costs by an estimated 20–30%, though your results vary depending on write frequency and retention policies.

Right-size your Apache Flink resources based on actual throughput needs. Start with a minimal configuration and scale up based on observed backpressure and checkpoint duration metrics. Use Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances where workload interruptions are acceptable, for example, in development and testing environments.

Set data retention policies on both your Apache Iceberg tables and checkpoint storage to avoid storing data longer than necessary.

Security

Security is a shared responsibility between you and AWS. AWS is responsible for the security of the cloud, including the hardware, software, networking, and facilities that run AWS services. You are responsible for security in the cloud, configuring access controls, encrypting data, and managing your application security. Apply these controls in priority order.

AWS IAM roles — Use AWS IAM roles with least-privilege access, scoped to specific resources. The following example policy restricts permissions to your data lake bucket and AWS Glue catalog:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["s3:GetObject", "s3:PutObject"],
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>/*"
    },
    {
      "Effect": "Allow",
      "Action": "s3:ListBucket",
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>",
      "Condition": {
        "StringEquals": {
          "aws:SourceVpce": "<your-vpc-endpoint-id>"
        }
      }
    },
    {
      "Effect": "Allow",
      "Action": ["glue:GetDatabase", "glue:GetTable"],
      "Resource": [
        "arn:aws:glue:us-east-1:<account-id>:catalog",
        "arn:aws:glue:us-east-1:<account-id>:database/streaming_db",
        "arn:aws:glue:us-east-1:<account-id>:table/streaming_db/*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
      "Resource": "arn:aws:kms:us-east-1:<account-id>:key/<your-kms-key-id>"
    }
  ]
}

Scoping permissions to specific Amazon S3 buckets, AWS Glue databases, and AWS Key Management Service (AWS KMS) keys restrict access to only the resources your pipeline requires. Review IAM policies quarterly using the IAM Access Analyzer to identify and remove unused permissions.

Encryption — Configure server-side encryption with AWS Key Management Service (AWS KMS) customer managed keys (SSE-KMS) for your Amazon S3 buckets. Using customer managed keys requires additional review from your security team. Confirm your key management policies, rotation procedures, and access controls before implementation. Enable automatic key rotation annually. For encryption in transit, enforce TLS by adding a bucket policy that denies non-HTTPS access:

{
  "Effect": "Deny",
  "Principal": "*",
  "Action": ["s3:GetObject", "s3:PutObject", "s3:ListBucket"],
  "Resource": [
    "arn:aws:s3:::<example-data-lake-bucket>/*",
    "arn:aws:s3:::<example-data-lake-bucket>"
  ],
  "Condition": {
    "Bool": { "aws:SecureTransport": "false" }
  }
}

Amazon S3 bucket hardening — Enable Block Public Access on your buckets to prevent accidental public exposure:

aws s3api put-public-access-block \
  --bucket <example-data-lake-bucket> \
  --public-access-block-configuration \
  BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

Enable versioning on buckets that store critical data and checkpoints to protect against accidental deletion. For production environments with sensitive data, consider enabling MFA Delete on versioned buckets. Enable S3 server access logging to track requests for security auditing.

Amazon Virtual Private Cloud (Amazon VPC) –Use Amazon VPC endpoints for private communication between your Apache Flink cluster and AWS services, removing public internet routing by keeping traffic within the AWS network.

Access logging – Enable AWS CloudTrail data events to log Amazon S3 object-level API calls (GetObject, PutObject) and Data Catalog API calls. Store logs in a separate Amazon S3 bucket with restricted access and enable log file integrity validation. Run regular compliance checks using AWS Config.

Operational practices

Set up a continuous integration and continuous deployment (CI/CD) pipeline to automate deployment and testing. Use version control to track schema and code changes. With Apache Iceberg’s schema evolution support, you can add columns without rewriting existing data files. Establish rollback procedures using Apache Iceberg’s snapshot-based architecture, so you can roll back to a previous table state if a bad write corrupts your data.

Troubleshooting

If you run into issues during setup or execution, use the following table to diagnose common errors.

Error Cause Solution
ClassNotFoundException Missing JAR files Check the dependencies in your lib directory and confirm HADOOP_CLASSPATH points to the correct path
Table not found Database name mismatch Check that the database name in t_env.use_database() matches the AWS Glue database where you registered your table
Checkpoint failures Amazon S3 permissions Check that your Amazon S3 bucket policy grants s3:PutObject for the checkpoint location
AWS credential errors Missing AWS IAM configuration Check that the AWS IAM role attached to your Apache Flink application has glue:GetTable, glue:GetDatabase, and s3:GetObject permissions on the relevant resources
Snapshot not found Table modified during query Increase monitor-interval or implement retry logic in your process_record() function
Schema mismatch Table schema changed between snapshots Review Apache Iceberg schema evolution settings and confirm backward compatibility

Clean up

To avoid ongoing charges, delete the resources that you created during this walkthrough.

  1. Stop your Amazon Managed Service for Apache Flink application. Open the Amazon Managed Service for Apache Flink console, choose your application name, choose Stop, and confirm the action. Or use the AWS CLI:

aws kinesisanalyticsv2 stop-application --application-name your-app-name

  1. Delete the Amazon S3 buckets that you created for data storage and checkpoints. For instructions, see Deleting a bucket in the Amazon S3 User Guide.
  2. Remove the Apache Iceberg tables from your Data Catalog.
  3. Delete the AWS IAM roles and policies created specifically for this walkthrough.
  4. If you created an Amazon VPC or Amazon VPC endpoints for testing, delete those resources.

Conclusion

Maintaining separate streaming and batch pipelines doubles your infrastructure costs, creates data synchronization issues, and adds operational complexity that slows your team down. In this post, you replaced that dual-pipeline architecture with a single system built on Apache Iceberg and Amazon Managed Service for Apache Flink. You configured a Flink environment with the required JAR dependencies, connected it to Data Catalog, and implemented streaming queries that read new records incrementally with exactly-once processing semantics. The same data, the same storage layer, the same schema—accessible to both your real-time and batch consumers.

To extend this solution, try these next steps based on your use case:

  • If you’re processing high volumes (>10,000 records/sec): Start with partition pruning. Add PARTITIONED BY (date_column) to your table definition, this typically reduces query times by 60–80%.
  • If you need production monitoring: Implement custom Amazon CloudWatch metrics. Track checkpoint duration, records processed per second, and backpressure to catch issues before they impact your pipeline.
  • If you have variable workloads: Configure auto scaling for your Apache Flink cluster. See the Amazon Managed Service for Apache Flink Developer Guide for detailed guidance.

Share your implementation experience in the comments, your use case, data volumes, latency improvements, and cost reductions help other readers calibrate their expectations. To get started, try the Amazon Managed Service for Apache Flink Developer Guide and the Apache Iceberg documentation on the Apache Iceberg website.


About the authors

Headshot of Nikhil

Nikhil Jha

Nikhil Jha is a Principal Delivery Consultant at AWS Professional Services, helping enterprises navigate complex modernization journeys. He builds data and AI solutions for AWS customers. Outside of work he likes swimming and hiking.

Headshot of Vyas

Vyas Garigipati

Vyas Garigipati is a Delivery Consultant at AWS Professional Services, with experience building scalable, distributed systems. He specializes in designing and building AI-powered, high-availability, multi-region architectures and helps customers deploy resilient, production ready solutions on AWS.

Headshot of Vafa

Vafa Ahmadiyeh

Vafa Ahmadiyeh is a Principal Lead Technologist at AWS, specializing in cloud architecture for the global financial services sector. He partners with major financial institutions to modernize their infrastructure and accelerate their migration to AWS, with a focus on building secure, scalable distributed systems and platforms designed for highly regulated environments.

Headshot of Kaushal

Kaushal (KK) Agrawal

Kaushal (KK) Agrawal is a Principal Technology Delivery Leader for the Digital Native Segment of AWS Professional Services, working with top-tier customers to deliver innovation at the intersection of AI and Cloud.

Proactive monitoring for Amazon Redshift Serverless using AWS Lambda and Slack alerts

Post Syndicated from Cristian Restrepo Lopez original https://aws.amazon.com/blogs/big-data/proactive-monitoring-for-amazon-redshift-serverless-using-aws-lambda-and-slack-alerts/

Performance issues in analytics environments often remain invisible until they disrupt dashboards, delay ETL jobs, or impact business decisions. For teams running Amazon Redshift Serverless, unmonitored query queues, long-running queries, or unexpected spikes in compute capacity can degrade performance and increase costs if left undetected.

Amazon Redshift Serverless streamlines running analytics at scale by removing the need to provision or manage infrastructure. However, even in a serverless environment, maintaining visibility into performance and usage is essential for efficient operation and predictable costs. While Amazon Redshift Serverless provides advanced built-in dashboards for monitoring performance metrics, delivering notifications directly to platforms like Slack, brings another level of agility. Real-time alerts in the team’s workflow enable faster response times and more informed decision-making without requiring constant dashboard monitoring.

In this post, we show you how to build a serverless, low-cost monitoring solution for Amazon Redshift Serverless that proactively detects performance anomalies and sends actionable alerts directly to your selected Slack channels. This approach helps your analytics team identify and address issues early, often before your users notice a problem.

Solution overview

The solution presented in this post uses AWS services to collect key performance metrics from Amazon Redshift Serverless, evaluate them against thresholds that you can flexibly configure, and notify you when anomalies are detected.

scope of solution

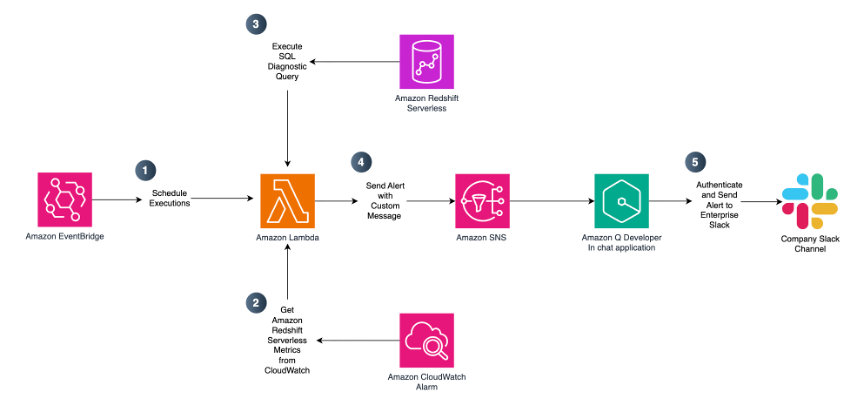
The workflow operates as follows:

  1. Scheduled execution – An Amazon EventBridge rule triggers an AWS Lambda function on a configurable schedule (by default, every 15 minutes during business hours).
  2. Metric collection – The AWS Lambda function gathers metrics including queued queries, running queries, compute capacity (RPUs), data storage usage, table count, database connections, and slow-running queries using Amazon CloudWatch and the Amazon Redshift Data API.
  3. Threshold evaluation – Collected metrics are compared against your predefined thresholds that reflect acceptable performance and usage limits.
  4. Alerting – When a threshold is exceeded, the Lambda function publishes a notification to an Amazon SNS topic.
  5. Slack notification – Amazon Q Developer in Chat applications (formerly AWS Chatbot) delivers the alert to your designated Slack channel.
  6. Observability – Lambda execution logs are stored in Amazon CloudWatch Logs for troubleshooting and auditing.

This architecture is fully serverless and requires no changes to your existing Amazon Redshift Serverless workloads. To simplify deployment, we provide an AWS CloudFormation template that provisions all required resources.

Prerequisites

Before deploying this solution, you must collect information about your existing Amazon Redshift Serverless workgroup and namespace that you want to monitor. To identify your Amazon Redshift Serverless resources:

  1. Open the Amazon Redshift console.
  2. In the navigation pane, choose Serverless dashboard.
  3. Note down your workgroup and namespace names. You will use these values when launching this blog’s AWS CloudFormation template.

Deploy the solution

You can launch the CloudFormation stack and deploy the solution via the provided link.

GitHub Repo

When launching the CloudFormation stack, complete the following steps in the AWS CloudFormation Console:

  1. For Stack name, enter a descriptive name such as redshift-serverless-monitoring.
  2. Review and modify the parameters as needed for your environment.
  3. Acknowledge that AWS CloudFormation may create IAM resources with custom names.
  4. Choose Submit.

CloudFormation parameters

Amazon Redshift Serverless Workgroup configuration

Provide details for your existing Amazon Redshift Serverless environment. These values connect the monitoring solution to your Redshift environment. Some parameters come with the default values that you can replace with your actual configuration.

Parameter Default value Description
Amazon Redshift Workgroup Name Your Amazon Redshift Serverless workgroup name.
Amazon Redshift Namespace Name Your Amazon Redshift Serverless namespace name.
Amazon Redshift Workgroup ID Workgroup ID (UUID) of the Amazon Redshift Serverless workgroup to monitor. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Namespace ID (UUID) of the Amazon Redshift Serverless namespace. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Database Name dev Target Amazon Redshift database for SQL-based diagnostic and monitoring queries.

Monitoring schedule

The default schedule runs diagnostic SQL queries every 15 minutes during business hours, balancing responsiveness and cost efficiency. Running more frequently might increase costs, while less frequent monitoring could delay detection of performance issues. You can adjust this schedule to your actual need.

Parameter Default value Description
Schedule Expression cron(0/15 8-17 ? * MON-FRI *) EventBridge schedule expression for Lambda function execution. Default runs every 15 minutes, Monday through Friday, 8 AM to 5 PM UTC.

Threshold configuration

Thresholds should be tuned based on your workload characteristics.

Parameter Default value Description
Queries Queued Threshold 20 Alerts threshold for queued queries.
Queries Running Threshold 20 Alerts threshold for running queries.
Compute Capacity Threshold (RPUs) 64 Alert threshold for compute capacity (RPUs).
Data Storage Threshold (MB) 5242880 Threshold for data storage in MB (default 5 TB).
Table Count Threshold (MB) 1000 Alerts threshold for total table count.
Database Connections Threshold 50 Alert threshold for database connections.
Slow Query Threshold (seconds) 10 Thresholds in seconds for slow query detection.
Query Timeout (Seconds) 30 Timeout for SQL diagnostics queries.

Tip: Start with conservative thresholds and refine them after observing baseline behavior for one to two weeks.

Lambda configuration

Configure the AWS Lambda function settings. The selected default values are appropriate for most monitoring scenarios. You may want to change them only in case of troubleshooting.

Parameter Default value Description
Lambda Memory Size (MB) 256 Lambda function memory size in MB.
Lambda Time Out (Seconds) 240 Lambda function timeout in seconds.

Security Configuration – Amazon Virtual Private Cloud (VPC)

If your organization has network isolation requirements, you can optionally enable VPC deployment for the Lambda function. When enabled, the Lambda function runs within your specified VPC subnets, providing network isolation and allowing access to VPC-only resources.

Parameter Default value Description
VPC ID VPC ID for Lambda deployment (required if EnableVPC is true). The Lambda function will be deployed in this VPC. Ensure that the VPC has appropriate routing (NAT Gateway or VPC Endpoints) to allow Lambda to access AWS services like CloudWatch, Amazon Redshift, and Amazon SNS.
VPC Subnet IDs Comma-separated list of subnet IDs for Lambda deployment (required if EnableVPC is true).
Security Group IDs Comma-separated list of security group IDs for Lambda (optional). If not provided and EnableVPC is true, a default security group will be created with outbound HTTPS access. Custom security groups must allow outbound HTTPS (port 443) to AWS service endpoints.

Note that VPC deployment might increase cold start times and requires an NAT Gateway or VPC endpoints for AWS service access. We recommend provisioning interface VPC endpoints (through AWS PrivateLink) for the five services the Lambda function calls which keeps all traffic private without the recurring cost of a NAT Gateway.

Security configuration – Encryption

If your organization requires encryption of data at rest, you can optionally enable AWS Key Management Service (AWS KMS) encryption for the Lambda function’s environment variables, CloudWatch Logs, and SNS topic. When enabled, the template encrypts each resource using the AWS KMS keys that you provide, either a single shared key for all three services, or individual keys for granular key management and audit separation.

Parameter Default value Description
Shared KMS Key ARN AWS KMS key ARN to use for all encryption (Lambda, Logs, and SNS) unless service-specific keys are provided. This streamlines key management by using a single key for all services. The key policy must grant encrypt/decrypt permissions to Lambda, CloudWatch Logs, and SNS.
Lambda KMS Key ARN AWS KMS key ARN for Lambda environment variable encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant decrypt permissions to the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
CloudWatch Logs KMS Key ARN AWS KMS key ARN for CloudWatch Logs encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to the CloudWatch Logs service. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
SNS Topic KMS Key ARN AWS KMS key ARN for SNS topic encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to SNS service and the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
Enable Dead Letter Queue False Optionally enable Dead Letter Queue (DLQ) for failed Lambda invocations to improve reliability and security monitoring. When enabled, events that fail after all retry attempts will be sent to an SQS queue for investigation and potential replay. This helps prevent data loss, provides visibility into failures, and enables security audit trails for monitoring anomalies. The DLQ retains messages for 14 days.

Note that AWS KMS encryption requires the key policy to grant appropriate permissions to each consuming service (Lambda, CloudWatch Logs, and SNS).

  1. On the review page, select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  2. Choose Submit.

Resources created

The CloudFormation stack creates the following resources:

  • EventBridge rule for scheduled execution
  • AWS Lambda function (Python 3.12 runtime)
  • Amazon SNS topic for alerts
  • IAM role with permissions for CloudWatch, Amazon Redshift Data API, and SNS
  • CloudWatch Log Group for Lambda logs

Note: CloudFormation deployment typically takes 10–15 minutes to complete. You can monitor progress in real time under the Events tab of your CloudFormation stack.

Post-deployment configuration

After the CloudFormation stack has been successfully created, complete the following steps.

Step 1: Record CloudFormation outputs

  1. Navigate to the AWS CloudFormation console.
  2. Select your stack and choose the Outputs tab.
  3. Note the values for LambdaRoleArn and SNSTopicArn. You will need these in subsequent steps.

Step 2: Grant Amazon Redshift permissions

Grant permissions to the Lambda function to query Amazon Redshift system tables for monitoring data. Complete the following steps to grant the necessary access:

  1. Navigate to the Amazon Redshift console.
  2. In the left navigation pane, choose Query Editor V2.
  3. Connect to your Amazon Redshift Serverless workgroup.
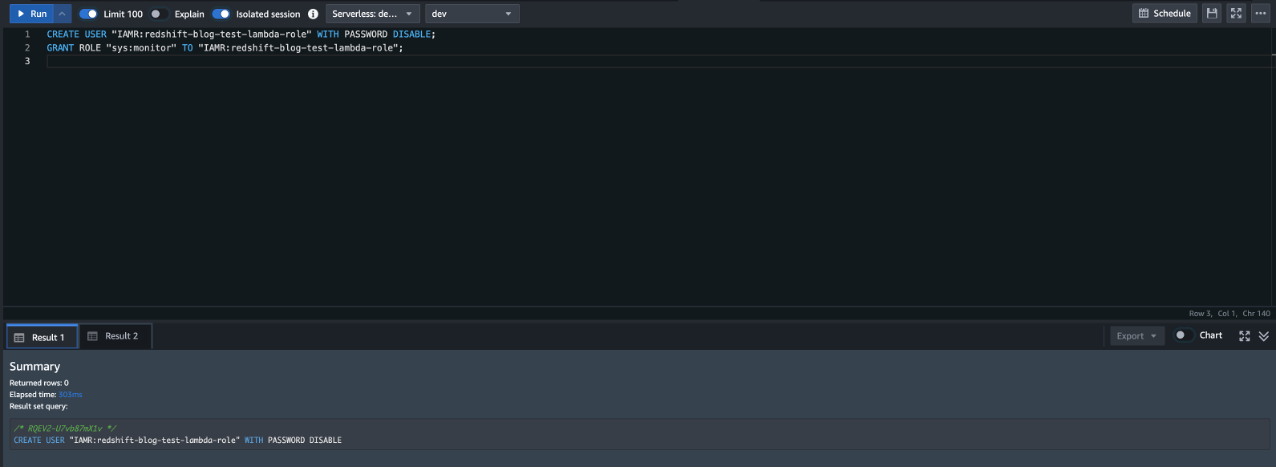
  4. Execute the following SQL commands, replacing <IAM Role ARN> with the LambdaRoleArn value from your CloudFormation outputs:
CREATE USER "IAMR:<IAM Lambda Role>" WITH PASSWORD DISABLE;

GRANT ROLE "sys:monitor" TO "IAMR:<IAM Role>";

RedshiftSQL-DBD-5612

These commands create an AmazonRedshift user associated with the Lambda IAM role and grant it the sys:monitor Amazon Redshift role. This role provides read-only access to catalog and system tables without granting permissions to user data tables.

Step 3: Configure Slack notifications

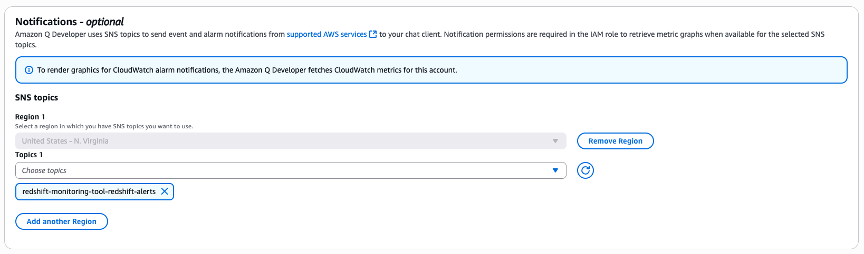
Amazon Q Developer in chat applications provides native AWS integration and managed authentication, removing custom webhook code and reducing setup complexity. To receive alerts in Slack, configure Amazon Q Developer in Chat Applications to connect your SNS topic to your preferred Slack channel:

  1. Navigate to Amazon Q Developer in chat applications (formerly AWS Chatbot) in the AWS console.
  2. Follow the instructions in the Slack integration documentation to authorize AWS access to your Slack workspace.
  3. When configuring the Slack channel, ensure that you select the correct AWS Region where you deployed the CloudFormation stack.
  4. In the Notifications section, select the SNS topic created by your CloudFormation stack (refer to the SNSTopicArn output value).
  5. Keep the default IAM read-only permissions for the channel configuration.

SNS topic

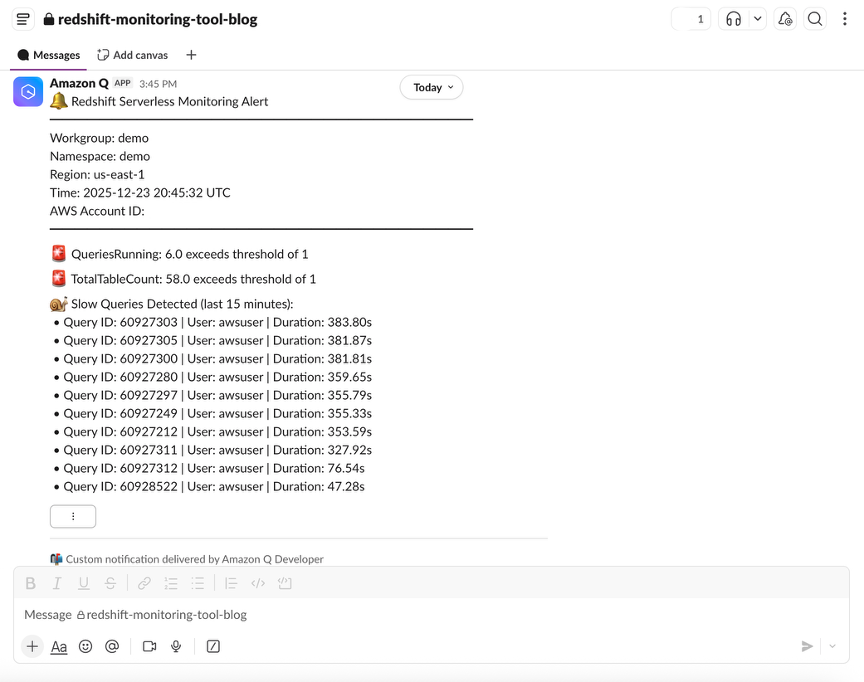
After configured, alerts automatically appear in Slack whenever thresholds are exceeded.

result-upon-success

Cost considerations

With the default configuration, this solution incurs minimal ongoing costs. The Lambda function executes approximately 693 times per month (every 15 minutes during an 8-hour business day, Monday through Friday), resulting in a monthly cost of approximately $0.33 USD. This includes Lambda compute costs ($0.26) and CloudWatch GetMetricData API calls ($0.07). All other services (EventBridge, SNS, CloudWatch Logs, and Amazon Redshift Data API). The Amazon Redshift Data API has no additional charges beyond the minimal Amazon Redshift Serverless RPU consumption for the Amazon Redshift Serverless system table query execution. You can reduce costs by decreasing the monitoring frequency (such as, every 30 minutes) or increase responsiveness by running more frequently (such as, every 5 minutes) with a proportional cost increase.

All costs are estimates and may vary based on your environment. Variations often occur because queries scanning system tables may take longer or require additional resources depending on the system complexity

Security best practices

This solution implements the following security controls:

  • IAM policies scoped to specific resource ARNs for the Amazon Redshift workgroup, namespace, SNS topic, and log group.
  • Data API statement access restricted to the Lambda function’s own IAM user ID.
  • Read-only sys:monitor database role for operational metadata access. Limit to the role created by the CloudFormation template.
  • Reserved concurrent executions capped at five.

To further strengthen your security posture, consider the following enhancements:

  • Enable EnableKMSEncryption to encrypt environment variables, logs, and SNS messages at rest.
  • Enable EnableVPC to deploy the function within a VPC for network isolation.
  • Audit access through AWS CloudTrail.

Important: This is sample code for non-production usage. Work with your security and legal teams to meet your organizational security, regulatory, and compliance requirements before deployment. This solution demonstrates monitoring capabilities but requires additional security hardening for production environments, including encryption configuration, IAM policy scoping, VPC deployment, and comprehensive testing.

Clean up

To remove all resources and avoid ongoing charges if you don’t want to use the solution anymore:

  1. Delete the CloudFormation stack.
  2. Remove the Slack integration from Amazon Q Developer in chat applications.

Troubleshooting

  • If no metrics or incomplete SQL diagnostics are returned, verify that the Amazon Redshift Serverless workgroup is active with recent query activity, and ensure the database user has the sys:monitor role (GRANT ROLE sys:monitor TO <user>) in the query editor. Without this role, queries execute successfully but only return data visible to that user’s permissions rather than the full cluster activity.
  • For VPC-deployed functions that fail to reach AWS services, confirm that VPC endpoints or a NAT Gateway are configured for CloudWatch, Amazon Redshift Data API, Amazon Redshift Serverless, SNS, and CloudWatch Logs.
  • If the Lambda function times out, increase the LambdaTimeout and QueryTimeoutSeconds parameters. The default timeout of 240 seconds accommodates most workloads, but clusters with many active queries may require additional time for SQL diagnostics to complete.

Conclusion

In this post, we showed how you can build a proactive monitoring solution for Amazon Redshift Serverless using AWS Lambda, Amazon CloudWatch, and Amazon SNS with Slack integration. By automatically collecting metrics, evaluating thresholds, and delivering alerts in near real time to Slack or your preferred collaborative platform, this solution helps detect performance and cost issues early. Because the solution itself is serverless, it aligns with the operational simplicity goals of Amazon Redshift Serverless—scaling automatically, requiring minimal maintenance, and delivering high value at low cost. You can extend this foundation with additional metrics, diagnostic logic, or alternative notification channels to meet your organization’s needs.

To learn more, see the Amazon Redshift documentation on monitoring and performance optimization.


About the authors

Headhost author 1

Cristian Restrepo Lopez

Cristian is a Solutions Architect at AWS, helping customers build modern data applications with a focus on analytics. Outside of work, he enjoys exploring emerging technologies and connecting with the data community.

Satesh Sonti

Satesh is a Principal Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Amazon EMR HBase on Amazon S3 transitioning to EMR S3A with comparable EMRFS performance

Post Syndicated from Dong Li original https://aws.amazon.com/blogs/big-data/amazon-emr-hbase-on-amazon-s3-transitioning-to-emr-s3a-with-comparable-emrfs-performance/

Starting with version 7.10, Amazon EMR is transitioning from EMR File System (EMRFS) to EMR S3A as the default file system connector for Amazon Simple Storage Service (Amazon S3) access. This transition brings HBase on Amazon S3 to a new level, offering performance parity with EMRFS while delivering substantial improvements, including better standardization, improved portability, stronger community support, improved performance through non-blocking I/O, asynchronous clients, and better credential management with AWS SDK V2 integration.

In this post, we discuss this transition and its benefits.

Understanding file system usage in HBase with Amazon EMR

HBase on Amazon S3 uses Amazon S3 as the primary storage layer instead of HDFS. When the memstore gets flushed, HBase writes HFiles directly to Amazon S3 using the file system connector. The Write Ahead Logs (WALs) and other operational files are still maintained in HDFS on the local cluster for performance and durability reasons. Amazon EMR also provides durable off-cluster EMR WAL implementation to improve the durability of the data.

With the HBase on Amazon S3 architecture, you can take advantage of the virtually unlimited storage capacity and cost-effectiveness of Amazon S3 while maintaining acceptable read/write performance. When data is read, HBase retrieves the HFiles directly from Amazon S3, and the block cache in memory helps optimize frequent read operations. This design alleviates the need for a large HDFS cluster for data storage, reducing operational costs and management overhead. The Amazon S3 file system connector handles the communication between HBase and Amazon S3, managing aspects like authentication, retry logic, and consistency. However, this setup might have slightly higher latency compared to traditional HBase on HDFS due to the network calls to Amazon S3, but the trade-off is justified by the benefits of scalability, caching layer, and cost-effectiveness that Amazon S3 provides.

Performance comparison of EMR S3A with EMRFS and OSS S3A from 7.3 release

Amazon EMR is transitioning how it connects to Amazon S3 storage. Through Amazon EMR 7.9, Amazon EMR has used EMRFS as its primary connector to interact with Amazon S3 for HBase storage. HBase on Amazon S3 significantly improved its performance with EMR S3A starting from the 7.3 release comparing to OSS S3A and matching the performance levels of EMRFS. This enhancement was thoroughly tested using Yahoo! Cloud Serving Benchmark (YCSB) workloads with 100 million rows in Amazon EMR 7.3 (using Hadoop 3.3 with AWS SDK V1) and Amazon EMR 7.10 (using Hadoop 3.4 with AWS SDK V2).

YCSB includes various workloads with different read and write proportions and data distribution patterns, such as:

  • Workload A (50% reads, 50% writes) – Simulates a scenario with equal read and write operations (50% each). This is ideal for applications requiring frequent updates and reads, such as session stores.
  • Workload B (95% reads, 5% writes) – Models a read-heavy application with 95% reads and 5% writes. This is well-suited for scenarios where retrieval operations dominate, like content delivery networks.
  • Workload C (100% reads) – Simulates user profile cache patterns and serves as a content delivery system.
  • Workload D (read latest data) – Simulates user status updates where users want to read the latest status.
  • Workload E (scan heavy) – Simulates threaded conversations where users scan through message threads.
  • Workload F (read/modify/write operations) – Simulates user record update patterns such as online gaming platforms where player scores are frequently read and updated based on game outcomes.

The performance comparison between EMRFS, EMR S3A, and OSS S3A for Amazon EMR 7.3 (AWS SDK V1) and 7.10 (AWS SDK V2) are illustrated in the following graphs, showing substantial improvements across different workload types. The graphs demonstrate how Amazon EMR 7.3 and 7.10 with EMR S3A achieve performance metrics comparable with EMRFS and up to 65% faster than OSS S3A, especially in read-heavy and mixed read/write workloads.


EMR S3A as the default file system from Amazon EMR 7.10

These performance improvements demonstrate a significant evolution in the capabilities of Amazon EMR. Well before EMR S3A became the default file system in version 7.10, EMR HBase users were already experiencing enhanced Amazon S3 access performance through EMR S3A. The critical enhancements implemented in Amazon EMR 7.3 successfully minimized the performance differential between EMRFS and EMR S3A for HBase operations. This achievement delivered optimal performance to users while preserving EMR S3A’s distinct benefits within the analytics ecosystem, including improved standardization, better community integration, and enhanced portability.

Amazon EMR 7.10 marks a significant change for HBase on Amazon S3 users. EMR S3A becomes the default file system connector automatically, independent of how your root directory’s file system is configured. This seamless transition enables EMR HBase customers to use EMR S3A’s expanding feature set and improvements without manual intervention.

Conclusion

The evolution of file system connectors in EMR HBase demonstrates AWS’s commitment to delivering high-performance, scalable solutions for big data workloads. Starting with EMR S3A, which achieved performance parity with EMRFS in Amazon EMR 7.3 (as validated through extensive YCSB benchmark tests with 100 million rows) and improvement over OSS S3A, to the upcoming transition to S3A as the default connector in Amazon EMR 7.10, AWS continues to enhance its storage interface capabilities.

The transition represents more than just a technical upgrade; it delivers a trifecta of benefits: enhanced standardization across Hadoop ecosystems, improved workload portability, and robust community support. Most importantly, this advancement maintains the high-performance standards established by EMRFS while positioning EMR HBase for future innovations in storage interface capabilities. AWS’s strategic evolution of file system connectors demonstrates its commitment to providing enterprise-grade solutions that combine performance, scalability, and architectural excellence.

As big data workloads continue to grow and evolve, this foundation of reliable, high-performance storage access will become increasingly crucial for organizations using EMR HBase for their data processing needs. We recommend that you stay up to date with the latest Amazon EMR release to take advantage of the latest performance and feature benefits.


About the Authors

Dong Li

Dong Li

Dong is a Senior Software development engineer for Amazon EMR at Amazon Web Services. His expertise is in big data systems, including Hadoop, HBase, and Hive. His customer obsession and dedication towards solving big data system problems helps Amazon EMR achieve more performance improvements.

Ramesh Kandasamy

Ramesh Kandasamy

Ramesh is an Engineering Manager for Amazon EMR at Amazon Web Services. He is a long tenured Amazonian dedicated to solving distributed system problems.

Giovanni Matteo Fumarola

Giovanni Matteo Fumarola

Giovanni is the Senior Manager for the Amazon EMR Spark and Iceberg group. He is an Apache Hadoop Committer and PMC member. He has been focusing on the big data analytics space since 2013.

Orchestrating big data processing with AWS Step Functions Distributed Map

Post Syndicated from Biswanath Mukherjee original https://aws.amazon.com/blogs/compute/orchestrating-big-data-processing-with-aws-step-functions-distributed-map/

Developers seek to process and enrich semi-structured big data datasets with durably orchestrated network-based workflows. For example, during quarterly earnings season, finance organizations run thousands of market simulations simultaneously to provide timely insights for scenario planning or risk management—these workloads require coordination between raw datasets and on-premise servers to provide the latest market information.

AWS Step Functions is a visual workflow service capable of orchestrating over 14,000 API actions from over 220 AWS services to build distributed applications. Now, Step Functions Distributed Map streamlines big data dataset transformation by processing Amazon Athena data manifest and Parquet files directly. Using its Distributed Map feature, you can process large scale datasets by running concurrent iterations across data entries in parallel. In Distributed mode, the Map state processes the items in the dataset in iterations called child workflow executions. You can specify the number of child workflow executions that can run in parallel. Each child workflow execution has its own, separate execution history from that of the parent workflow. By default, Step Functions runs 10,000 parallel child workflow executions in parallel.

Distributed Map can process AWS Athena data manifest and Parquet files directly, eliminating the need for custom pre-processing. You also now have visibility into your Distributed Map usage with new Amazon CloudWatch metrics: Approximate Open Map Runs Count, Open Map Run Limit, and Approximate Map Runs Backlog Size.

In this post, you’ll learn how to use AWS Step Functions Distributed Map to process Athena data manifest and Parquet files through a step-by-step demonstration.

This post is part of a series of post about AWS Step Functions Distributed Map:

Use case: IoT sensor data processing

You’ll build a sample application that demonstrates processing IoT sensor data in Parquet format using Step Functions Distributed Map. These Parquet data files and a manifest file containing the list of the data files are exported from Athena. The data temperature, humidity, and lbattery level from different devices. The following table shows sample of sensor data:

Example IoT sensor data

Example IoT sensor data

Your objective is to use the Athena data manifest file, get the list of Parquet files, and iterate over the data in the files to detect anomalies and also stream the processed data through Amazon Kinesis Data Firehose to an Amazon S3 bucket for further analytics using Athena queries. Following is the criteria to detect anomaly:

  • Low battery conditions: less than 20%
  • Humidity anomalies: more than 95% or less than 5%
  • Temperature spikes: more than 35°C or less than -10°C

The following diagram represents the AWS Step Functions state machine:

Parquet files processing workflow

Parquet files processing workflow

  1. The Distributed Map runs an Athena query which generates Parquet data files and an Athena manifest file (csv). The manifest file contains the list of Parquet data files.
  2. Distributed Map processes these Parquet data files in parallel using child workflow executions. You can control the number of child workflow executions that can run in parallel using MaxConcurrency parameter. See Step Functions service quotas to learn more about concurrency limits.
  3. Each child workflow execution invokes an AWS Lambda function to process the respective Parquet file. The Lambda function processes individual sensor readings and detects anomalies according to the preceeding logic and returns a processed sensor data summary response.
  4. The child workflow sends the summary response record to Amazon Kinesis firehose stream which stores the results in a specified Amazon S3 results bucket.

The following Athena Start QueryExecution state runs an UNLOAD query to generate data files in Parquet format and a manifest file in CSV. The output will be stored in the S3 bucket specified in the UNLOAD query and the manifest file will be stored in the S3 bucket configured for the Athena workgroup.

{
  "QueryLanguage": "JSONata",
  "States": {
	   "Athena StartQueryExecution": {
	    "Type": "Task",
	        "Resource": "arn:aws:states:::athena:startQueryExecution.sync",
	        "Arguments": {
		"QueryString": "UNLOAD (WRITE_YOUR_SELECT_QUERY_HERE) TO 'S3_URI_FOR_STORING_DATA_OBJECT' WITH (format = 'JSON')",
		"WorkGroup": "primary"
	},
	"Output": {
	"ManifestObjectKey": "{% $join([$states.result.QueryExecution.ResultConfiguration.OutputLocation, '-manifest.csv']) %}"
},
“Next”: “Next State”
…
}

The following ItemReader is configured to use a manifest type of “ATHENA_DATA” with “PARQUET” data input.

{
  "QueryLanguage": "JSONata",
  "States": {
    ...
    "Map": {
        ...
        "ItemReader": {
        	"Resource": "arn:aws:states:::s3:getObject",
   	"ReaderConfig": {
      		"ManifestType": "ATHENA_DATA",
      		"InputType": "PARQUET"
   	},
   	"Arguments": {
      		"Bucket":"Bucket": "{% $split($substringAfter($states.input.ManifestObjectKey, 's3://'), '/')[0] %}",,
      		"Key": "{% $substringAfter($substringAfter($states.input.ManifestObjectKey, 's3://'), '/') %}"
   	}
	    },
        ...
    }
}

Additional supported InputType options are CSV and JSONL. All objects referenced in a single manifest file must have the same InputType format. You specify the Amazon S3 bucket location of Athena manifest CSV file under Arguments.

The context object contains information in a JSON structure about your state machine and execution. Your workflows can reference the context object in a JSONata expression with $states.context.

Within a Map state, the Context object includes the following data:

"Map": {
   "Item": {
      "Index" : Number,
      "Key"   : "String", // Only valid for JSON objects
      "Value" : "String",
      "Source": "String"
   }
}

For each Map state iteration, Index contains the index number for the array item that is being currently processed, Key is available only when iterating over JSON objects, Value contains the array item being processed, and Source contains one of the following:

  • For state input, the value will be : STATE_DATA
  • For Amazon S3 LIST_OBJECTS_V2 with Transformation=NONE, the value will show the S3 URI for the bucket. For example: S3://amzn-s3-demo-bucket.
  • For all the other input types, the value will be the Amazon S3 URI. For example: S3://amzn-s3-demo-bucket/object-key.

Using this newly introduced Source field in the context object, you can connect the child executions with the source object.

Prerequisites

Set up the state machine and sample data

Run the following steps to deploy the Step Functions state machine.

  1. Clone the GitHub repository in a new folder and navigate to the project root folder.
    git clone https://github.com/aws-samples/sample-stepfunctions-athena-manifest-parquet-file-processor.git
    cd sample-stepfunctions-athena-manifest-parquet-file-processor

  2. Run the following command to install required Python dependencies for the Lambda function.
    python3 -m venv .venv
    source .venv/bin/activate
    python3 -m pip install -r requirements.txt

  3. Build the application.
    sam build

  4. Deploy the application
    sam deploy --guided

  5. Enter the following details:
    • Stack name: The CloudFormation stack name (for example, sfn-parquet-file-processor)
    • AWS Region: A supported AWS Region (for example, us-east-1)
    • Keep rest of the components to default values.

    Note the outputs from the AWS SAM deploy. You will use them in the subsequent steps.

  6. Run the following command to generate sample data in csv format and upload it to an S3 bucket. Replace <IoTDataBucketName> with the value from sam deploy ouptut.
    python3 scripts/generate_sample_data.py <IoTDataBucketName>

Create the Athena database and tables

Before you can run queries, you must set up an Athena database and table for your data.

  1. From Amazon Athena console, navigate to workgoups, select the workgroup named “primary”. Select Edit from Actions. In the query result configuration section, select the options as follows:
    1. Management of query results – select customer managed
    2. Location of query results – enter s3://<IoTDataBucketName>. Replace <IoTDataBucketName> with the value from sam deploy output.
    3. Choose Save to save the changes to the workgroup
  2. Select Query editor tab and run the following commands to create database and tables
    CREATE DATABASE `iotsensordata`;

  3. Create an Athena table in database iotsensordata that references the S3 bucket containing the raw sensor data. In this case it will be <IoTDataBucketName>. Replace <IoTDataBucketName> with the value from sam deploy output.
    CREATE EXTERNAL TABLE IF NOT EXISTS `iotsensordata`.`iotsensordata` 
    (`deviceid` string, 
    `timestamp` string,
    `temperature` double,
    `humidity` double,
    `batterylevel` double,
    `latitude` double,
    `longitude` double
    )
    ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe'
    WITH SERDEPROPERTIES ('field.delim' = ',')
    STORED AS INPUTFORMAT 'org.apache.hadoop.mapred.TextInputFormat' OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION 's3://<IoTDataBucketName>/daily-data/'
    TBLPROPERTIES (
     'classification' = 'csv',
     'skip.header.line.count' = '1'
    );

  4. Create an Athena table in database iotsensordata that references the S3 bucket having the analytics results streamed from Kinesis Data Firehose. Replace <IoTAnalyticsResultsBucket> with value from sam deploy output. And replace <year> with the current year (e.g 2025).
    CREATE EXTERNAL TABLE IF NOT EXISTS iotsensordata.iotsensordataanalytics (deviceid string, analysisDate string, readingTimestamp string, readingsCount int, metrics struct< temperature: double, humidity: double, batterylevel: double, latitude: double, longitude: double >, anomalies array <string>, anomalyCount int, healthStatus string, timestamp string )
    ROW FORMAT SERDE 'org.openx.data.jsonserde.JsonSerDe'
    WITH SERDEPROPERTIES ( 'ignore.malformed.json' = 'FALSE', 'dots.in.keys' = 'FALSE', 'case.insensitive' = 'TRUE'
    )
    STORED AS INPUTFORMAT 'org.apache.hadoop.mapred.TextInputFormat' OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
    LOCATION 's3://<IoTAnalyticsResultsBucket>/<year>/'
    TBLPROPERTIES ('classification' = 'json', 'typeOfData'='file');

Start your state machine

Now that you have data ready and Athena set up for queries, start your state machine to retrieve and process the data.

  1. Run the following command to start execution of the Step Functions. Replace the <StateMachineArn> and <IoTDataBucketName> with the value from sam deploy output..
    aws stepfunctions start-execution \
      --state-machine-arn <StateMachineArn> \
      --input '{ "IoTDataBucketName": "<IoTDataBucketName>"}'

    The Step Functions state machine has the Athena StartQueryExecution state which has an UNLOAD query that generates the sensor data files in a parquet format and a manifest file in CSV format. The manifest will have 5 rows referencing the 5 parquet files. The state machine will process these 5 parquet files in one map run.

  2. Run the following command to get the details of the execution. Replace the executionArn from the previous command.
    aws stepfunctions describe-execution --execution-arn <executionArn>

  3. After you see the status SUCCEEDED, run the following command from Athena query editor to check the processed output from Kinesis Data Firehose that was streamed to S3 bucket referenced by the Athena table created in step 4 of the preceding section.
    SELECT * FROM iotsensordata.iotsensordataanalytics WHERE anomalycount = 1;

If any of the sensor data exceeds the thresholds, the healthstatus attribute will be set to “anomalies_detected”. The workflow produced a summary table of metadata which you can now query for reporting.

Output from Athena Query Editor

Review workflow performance

Using the following observability metrics, you can review key performance behavior of your data processing workflow.
The AWS/States namespace includes the following new metrics for all Step Functions Map Runs.

  • OpenMapRunLimit: This is the maximum number of open Map Runs allowed in the AWS account. The default value is 1,000 runs and is a hard limit. For more information, see Quotas related to accounts.
  • ApproximateOpenMapRunCount: This metric tracks the approximate number of Map Runs currently in progress within an account. Configuring an alarm on this metric using the Maximum statistic with a threshold of 900 or higher can help you take proactive action before reaching the OpenMapRunLimit of 1,000. This metric enables operational teams to implement preventive measures, such as staggering new executions or optimizing workflow concurrency, to maintain system stability and prevent backlog accumulation.
  • ApproximateMapRunBacklogSize: This metric shows up when the ApproximateOpenMapRunCount has reached 1,000 and there are backlogged Map Runs waiting to be executed. Backlogged Map Runs wait at the MapRunStarted event until the total number of open Map Runs is less than the quota.

The following graph shows an example of these new metrics. Use the maximum statistic to visualize these metrics. ApproximateMapRunBacklogSize metrics appear after accounts start getting throttled on the OpenMapRunLimit limit. The OpenMapRun (orange line) is the account hard limit of 1,000 shown as a static line. The ApproximateOpenMapRunCount (violet line) is the current number of active OpenMap runs. The ApproximateMapRunBacklogSize (green line) indicates the map runs waiting in backlog to be processed. When the ApproximateOpenMapRunCount is lower than 1000 (OpenMapRun limit) there are no map runs in backlog. However, when the count reaches the OpenMapRun limit, the backlog of map runs starts to build up. After the active runs complete, the backlog will start to drain out and new runs will begin execution.

Graphed metrics from Amazon CloudWatch

Graphed metrics from Amazon CloudWatch

Clean up

To avoid costs, remove all resources created for this post once you’re done. From the Athena query editor, run the following commands:

DROP TABLE `iotsensordata`.`iotsensordata`;
DROP TABLE `iotsensordata`.`iotsensordataanalytics`;
DROP DATABASE `iotsensordata`;

Run the following commands from the AWS CLI after replacing the <placeholder> variable to delete the resources you deployed for this post’s solution:

aws s3 rm s3://<IoTDataBucketName> --recursive
aws s3 rm s3://<IoTAnalyticsResultsBucketName> --recursive
sam delete

Conclusion

With this update, Distributed Map now supports additional data inputs, so you can orchestrate large-scale analytics and ETL workflows. You can now process Amazon Athena data manifest and Parquet files directly, eliminating the need for custom pre-processing. You also now have visibility into your Distributed Map usage with the following metrics: Approximate Open Map Runs Count, Open Map Run Limit, and Approximate Map Runs Backlog Size.

New input sources for Distributed Map are available in all commercial AWS Regions where AWS Step Functions is available. For a complete list of AWS Regions where Step Functions is available, see the AWS Region Table. The improved observability of your Distributed Map usage with new metrics is available in all AWS Regions. To get started, you can use the Distributed Map mode today in the AWS Step Functions console. To learn more, visit the Step Functions developer guide.

For more serverless learning resources, visit Serverless Land.

The Amazon SageMaker Lakehouse Architecture now supports Tag-Based Access Control for federated catalogs

Post Syndicated from Sandeep Adwankar original https://aws.amazon.com/blogs/big-data/the-amazon-sagemaker-lakehouse-architecture-now-supports-tag-based-access-control-for-federated-catalogs/

The Amazon SageMaker lakehouse architecture has expanded its tag-based access control (TBAC) capabilities to include federated catalogs. This enhancement extends beyond the default AWS Glue Data Catalog resources to encompass Amazon S3 Tables, Amazon Redshift data warehouses. TBAC is also supported on federated catalogs from data sources Amazon DynamoDB, MySQL, PostgreSQL, SQL Server, Oracle, Amazon DocumentDB, Google BigQuery, and Snowflake. TBAC provides you a sophisticated permission management that uses tags to create logical groupings of catalog resources, enabling administrators to implement fine-grained access controls across their entire data landscape without managing individual resource-level permissions.

Traditional data access management often requires manual assignment of permissions at the resource level, creating significant administrative overhead. TBAC solves this by introducing an automated, inheritance-based permission model. When administrators apply tags to data resources, access permissions are automatically inherited, eliminating the need for manual policy modifications when new tables are added. This streamlined approach not only reduces administrative burden but also enhances security consistency across the data ecosystem.

TBAC can be set up through the AWS Lake Formation console, and accessible using Amazon Redshift, Amazon Athena, Amazon EMR, AWS Glue, and Amazon SageMaker Unified Studio. This makes it valuable for organizations managing complex data landscapes with multiple data sources and large datasets. TBAC is especially beneficial for enterprises implementing data mesh architectures, maintaining regulatory compliance, or scaling their data operations across multiple departments. Furthermore, TBAC enables efficient data sharing across different accounts, making it easier to maintain secure collaboration.

In this post, we illustrate how to get started with fine-grained access control of S3 Tables and Redshift tables in the lakehouse using TBAC. We also show how to access these lakehouse tables using your choice of analytics services, such as Athena, Redshift, and Apache Spark in Amazon EMR Serverless in Amazon SageMaker Unified Studio.

Solution overview

For illustration, we consider a fictional company called Example Retail Corp, as covered in the blog post Accelerate your analytics with Amazon S3 Tables and Amazon SageMaker Lakehouse. Example Retail’s leadership has decided to use the SageMaker lakehouse architecture to unify data across S3 Tables and their Redshift data warehouse. With this lakehouse architecture, they can now conduct analyses across their data to identify at-risk customers, understand the impact of personalized marketing campaigns on customer churn, and develop targeted retention and sales strategies.

Alice is a data administrator with the AWS Identity and Access Management (IAM) role LHAdmin in Example Retail Corp, and she wants to implement tag-based access control to scale permissions across their data lake and data warehouse resources. She is using S3 Tables with Iceberg transactional capability to achieve scalability as updates are streamed across billions of customer interactions, while providing the same durability, availability, and performance characteristics that S3 is known for. She already has a Redshift namespace, which contains historical and current data about sales, customers prospects, and churn information. Alice supports an extended team of developers, engineers, and data scientists who require access to the data environment to develop business insights, dashboards, ML models, and knowledge bases. This team includes:

  • Bob, a data steward with IAM role DataSteward, is the domain owner and manages access to the S3 Tables and warehouse data. He enables other teams who build reports to be shared with leadership.
  • Charlie, a data analyst with IAM role DataAnalyst, builds ML forecasting models for sales growth using the pipeline or customer conversion across multiple touchpoints, and makes those available to finance and planning teams.
  • Doug, a BI engineer with IAM role BIEngineer, builds interactive dashboards to funnel customer prospects and their conversions across multiple touchpoints, and makes those available to thousands of sales team members.

Alice decides to use the SageMaker lakehouse architecture to unify data across S3 Tables and Redshift data warehouse. Bob can now bring his domain data into one place and manage access to multiple teams requesting access to his data. Charlie can quickly build Amazon QuickSight dashboards and use his Redshift and Athena expertise to provide quick query results. Doug can build Spark-based processing with AWS Glue or Amazon EMR to build ML forecasting models.

Alice’s goal is to use TBAC to make fine-grained access much more scalable, because they can grant permissions on many resources at once and permissions are updated accordingly when tags for resources are added, changed, or removed.The following diagram illustrates the solution architecture.

Alice as Lakehouse admin and Bob as Data Steward determines that following high-level steps are needed to deploy the solution:

  1. Create an S3 Tables bucket and enable integration with the Data Catalog. This will make the resources available under the federated catalog s3tablescatalog in the lakehouse architecture with Lake Formation for access control. Create a namespace and a table under the table bucket where the data will be stored.
  2. Create a Redshift cluster with tables, publish your data warehouse to the Data Catalog, and create a catalog registering the namespace. This will make the resources available under a federated catalog in the lakehouse architecture with Lake Formation for access control.
  3. Delegate permissions to create tags and grant permissions on Data Catalog resources to DataSteward.
  4. As DataSteward, define tag ontology based on the use case and create Tags. Assign these LF-Tags to the resources (database or table) to logically group lakehouse resources for sharing based on access patterns.
  5. Share the S3 Tables catalog table and Redshift table using tag-based access control to DataAnalyst, who uses Athena for analysis and Redshift Spectrum for generating the report.
  6. Share the S3 Tables catalog table and Redshift table using tag-based access control to BIEngineer, who uses Spark in EMR Serverless to further process the datasets.

Data steward defines the tags and assignment to resources as shown:

Tags Data Resources

Domain = sales

Sensitivity = false

S3 Table:

customer(

c_salutation,              c_preferred_cust_flag,c_first_sales_date_sk,
c_customer_sk ,
c_login ,
c_current_cdemo_sk ,
c_current_hdemo_sk ,
c_current_addr_sk ,
c_customer_id ,
c_last_review_date_sk ,
c_birth_month ,
c_birth_country ,
c_birth_day ,
c_first_shipto_date_sk
)

Domain = sales

Sensitivity = true

S3 Table:

customer(

c_first_name,

c_last_name,

c_email_address,

c_birth_year)

Domain = sales

Sensitivity = false

Redshift Table:

sales.store_sales

The following table summarizes the tag expression that is granted to roles for resource access:

User Persona Permission Granted Access
Bob DataSteward SUPER_USER on catalogs Admin access on customer and store_sales.
Charlie DataAnalyst

Domain = sales

Sensitivity = false

Access to non -sensitive data that is aligned to sales domain: customer(non-sensitive columns) and store_sales.
Doug BIEngineer Domain = sales Access to all datasets that is aligned to sales domain: customer and store_sales.

Prerequisites

To follow along with this post, complete the following prerequisite steps:

  1. Have an AWS account and admin user with access to the following AWS services:
    1. Athena
    2. Amazon EMR
    3. IAM
    4. Lake Formation and the Data Catalog
    5. Amazon Redshift
    6. Amazon S3
    7. IAM Identity Center
    8. Amazon SageMaker Unified Studio
  2. Create a data lake admin (LHAdmin). For instructions, see Create a data lake administrator.
  3. Create an IAM role named DataSteward and attach permissions for AWS Glue and Lake Formation access. For instructions, refer to Data lake administrator permissions.
  4. Create an IAM role named DataAnalyst and attach permissions for Amazon Redshift and Athena access. For instructions, refer to Data analyst permissions.
  5. Create an IAM role named BIEngineer and attach permissions for Amazon EMR access. This is also the EMR runtime role that the Spark job will use to access the tables. For instructions on the role permissions, refer to Job runtime roles for EMR serverless.
  6. Create an IAM role named RedshiftS3DataTransferRole following the instructions in Prerequisites for managing Amazon Redshift namespaces in the AWS Glue Data Catalog.
  7. Create an EMR Studio and attach an EMR Serverless namespace in a private subnet to it, following the instructions in Run interactive workloads on Amazon EMR Serverless from Amazon EMR Studio.

Create data lake tables using an S3 Tables bucket and integrate with the lakehouse architecture

Alice completes the following steps to create a table bucket and enable integration with analytics services:

  1. Sign in to the Amazon S3 console as LHAdmin.
  2. Choose Table buckets in the navigation pane and create a table bucket.
  3. For Table bucket name, enter a name, such as tbacblog-customer-bucket.
  4. For Integration with AWS analytics services, choose Enable integration.
  5. Choose Create table bucket.
  6. After you create the table, click the hyperlink of the table bucket name.
  7. Choose Create table with Athena.
  8. Create a namespace and provide a namespace name. For example, tbacblog_namespace.
  9. Choose Create namespace.
  10. Now proceed to creating table schema and populating it by choosing Create table with Athena.
  11. On the Athena console, run the following SQL script to create a table:
    CREATE TABLE `tbacblog_namespace`.customer (
      c_salutation string, 
      c_preferred_cust_flag string, 
      c_first_sales_date_sk int, 
      c_customer_sk int, 
      c_login string, 
      c_current_cdemo_sk int, 
      c_first_name string, 
      c_current_hdemo_sk int, 
      c_current_addr_sk int, 
      c_last_name string, 
      c_customer_id string, 
      c_last_review_date_sk int, 
      c_birth_month int, 
      c_birth_country string, 
      c_birth_year int, 
      c_birth_day int, 
      c_first_shipto_date_sk int, 
      c_email_address string)
    TBLPROPERTIES ('table_type' = 'iceberg');
    
    
    INSERT INTO tbacblog_namespace.customer
    VALUES('Dr.','N',2452077,13251813,'Y',1381546,'Joyce',2645,2255449,'Deaton','AAAAAAAAFOEDKMAA',2452543,1,'GREECE',1987,29,2250667,'[email protected]'),
    ('Dr.','N',2450637,12755125,'Y',1581546,'Daniel',9745,4922716,'Dow','AAAAAAAAFLAKCMAA',2432545,1,'INDIA',1952,3,2450667,'[email protected]'),
    ('Dr.','N',2452342,26009249,'Y',1581536,'Marie',8734,1331639,'Lange','AAAAAAAABKONMIBA',2455549,1,'CANADA',1934,5,2472372,'[email protected]'),
    ('Dr.','N',2452342,3270685,'Y',1827661,'Wesley',1548,11108235,'Harris','AAAAAAAANBIOBDAA',2452548,1,'ROME',1986,13,2450667,'[email protected]'),
    ('Dr.','N',2452342,29033279,'Y',1581536,'Alexandar',8262,8059919,'Salyer','AAAAAAAAPDDALLBA',2952543,1,'SWISS',1980,6,2650667,'[email protected]'),
    ('Miss','N',2452342,6520539,'Y',3581536,'Jerry',1874,36370,'Tracy','AAAAAAAALNOHDGAA',2452385,1,'ITALY',1957,8,2450667,'[email protected]');
    
    SELECT * FROM tbacblog_namespace.customer;

You have now created the S3 Tables table customer, populated it with data, and integrated it with the lakehouse architecture.

Set up data warehouse tables using Amazon Redshift and integrate them with the lakehouse architecture

In this section, Alice sets up data warehouse tables using Amazon Redshift and integrates them with the lakehouse architecture.

Create a Redshift cluster and publish it to the Data Catalog

Alice completes the following steps to create a Redshift cluster and publish it to the Data Catalog:

  1. Create a Redshift Serverless namespace called salescluster. For instructions, refer to Get started with Amazon Redshift Serverless data warehouses.
  2. Sign in to the Redshift endpoint salescluster as an admin user.
  3. Run the following script to create a table under the dev database under the public schema:
    CREATE SCHEMA sales;
    CREATE TABLE sales.store_sales (
    sale_id INTEGER IDENTITY(1,1) PRIMARY KEY,
    customer_sk INTEGER NOT NULL,
    sale_date DATE NOT NULL,
    sale_amount DECIMAL(10, 2) NOT NULL,
    product_name VARCHAR(100) NOT NULL,
    last_purchase_date DATE
    );
    
    INSERT INTO sales.store_sales (customer_sk, sale_date, sale_amount, product_name, last_purchase_date)
    VALUES
    (13251813, '2023-01-15', 150.00, 'Widget A', '2023-01-15'),
    (29033279, '2023-01-20', 200.00, 'Gadget B', '2023-01-20'),
    (12755125, '2023-02-01', 75.50, 'Tool C', '2023-02-01'),
    (26009249, '2023-02-10', 300.00, 'Widget A', '2023-02-10'),
    (3270685, '2023-02-15', 125.00, 'Gadget B', '2023-02-15'),
    (6520539, '2023-03-01', 100.00, 'Tool C', '2023-03-01'),
    (10251183, '2023-03-10', 250.00, 'Widget A', '2023-03-10'),
    (10251283, '2023-03-15', 180.00, 'Gadget B', '2023-03-15'),
    (10251383, '2023-04-01', 90.00, 'Tool C', '2023-04-01'),
    (10251483, '2023-04-10', 220.00, 'Widget A', '2023-04-10'),
    (10251583, '2023-04-15', 175.00, 'Gadget B', '2023-04-15'),
    (10251683, '2023-05-01', 130.00, 'Tool C', '2023-05-01'),
    (10251783, '2023-05-10', 280.00, 'Widget A', '2023-05-10'),
    (10251883, '2023-05-15', 195.00, 'Gadget B', '2023-05-15'),
    (10251983, '2023-06-01', 110.00, 'Tool C', '2023-06-01'),
    (10251083, '2023-06-10', 270.00, 'Widget A', '2023-06-10'),
    (10252783, '2023-06-15', 185.00, 'Gadget B', '2023-06-15'),
    (10253783, '2023-07-01', 95.00, 'Tool C', '2023-07-01'),
    (10254783, '2023-07-10', 240.00, 'Widget A', '2023-07-10'),
    (10255783, '2023-07-15', 160.00, 'Gadget B', '2023-07-15');
    
    SELECT * FROM sales.store_sales;

  4. On the Redshift Serverless console, open the namespace.
  5. On the Actions dropdown menu, choose Register with AWS Glue Data Catalog to integrate with the lakehouse architecture.
  6. Select the same AWS account and choose Register.

Create a catalog for Amazon Redshift

Alice completes the following steps to create a catalog for Amazon Redshift:

  1. Sign in to the Lake Formation console as the data lake administrator LHAdmin.
  2. In the navigation pane, under Data Catalog, choose Catalogs.
    Under Pending catalog invitations, you will see the invitation initiated from the Redshift Serverless namespace salescluster.
  3. Select the pending invitation and choose Approve and create catalog.
  4. Provide a name for the catalog. For example, redshift_salescatalog.
  5. Under Access from engines, select Access this catalog from Iceberg-compatible engines and choose RedshiftS3DataTransferRole for IAM role.
  6. Choose Next.
  7. Choose Add permissions.
  8. Under Principals, choose the LHAdmin role for IAM users and roles, choose Super user for Catalog permissions, and choose Add.
  9. Choose Create catalog.After you create the catalog redshift_salescatalog, you can inspect the sub-catalog dev, namespace and database sales, and table store_sales underneath it.

Alice has now completed creating an S3table catalog table and Redshift federated catalog table in the Data Catalog.

Delegate LF-Tags creation and resource permission to the DataSteward role

Alice completes the following steps to delegate LF-Tags creation and resource permission to Bob as DataSteward:

  1. Sign in to the Lake Formation console as the data lake administrator LHAdmin.
  2. In the navigation pane, choose LF Tags and permissions, then choose the LF-Tag creators tab.
  3. Choose Add LF-Tag creators.
  4. Choose DataSteward for IAM users and roles.
  5. Under Permission, select Create LF-Tag and choose Add.
  6. In the navigation pane, choose Data permissions, then choose Grant.
  7. In the Principals section, for IAM users and roles, choose the DataSteward role.
  8. In the LF-Tags or catalog resources section, select Named Data Catalog resources.
  9. Choose <account_id>:s3tablescatalog/tbacblog-customer-bucket and <account_id>:redshift_salescatalog/dev for Catalogs.
  10. In the Catalog permissions section, select Super user for permissions.
  11. Choose Grant.

You can verify permissions for DataSteward on the Data permissions page.

Alice has now completed delegating LF-tags creation and assignment permissions to Bob, the DataSteward. She had also granted catalog level permissions to Bob.

Create LF-Tags

Bob as DataSteward completes the following steps to create LF-Tags:

  1. Sign in to the Lake Formation console as DataSteward.
  2. In the navigation pane, choose LF Tags and permissions, then choose the LF-tags tab.
  3. Choose Add-LF-Tag.
  4. Create LF tags as follows:
    1. Key: Domain and Values: sales, marketing
    2. Key: Sensitivity and Values: true, false

Assign LF-Tags to the S3 Tables database and table

Bob as DataSteward completes the following steps to assign LF-Tags to the S3 Tables database and table:

  1. In the navigation pane, choose Catalogs and choose s3tablescatalog.
  2. Choose tbacblog-customer-bucket and choose tbacblog_namespace.
  3. Choose Edit LF-Tags.
  4. Assign the following tags:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false
  5. Choose Save.
  6. On the View dropdown menu, choose Tables.
  7. Choose the customer table and choose the Schema tab.
  8. Choose Edit schema and select the columns c_first_name, c_last_name, c_email_address, and c_birth_year.
  9. Choose Edit LF-Tags and modify the tag value:
    1. Key: Sensitivity and Value: true
  10. Choose Save.

Assign LF-Tags to the Redshift database and table

Bob as DataSteward completes the following steps to assign LF-Tags to the Redshift database and table:

  1. In the navigation pane, choose Catalogs and choose salescatalog.
  2. Choose dev and select sales.
  3. Choose Edit LF-Tags and assign the following tags:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false
  4. Choose Save.

Grant catalog permission to the DataAnalyst and BIEngineer roles

Bob as DataSteward completes the following steps to grant catalog permission to the DataAnalyst and BIEngineer roles (Charlie and Doug, respectively):

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the DataAnalyst and BIEngineer roles.
  3. In the LF-Tags or catalog resources section, select Named Data Catalog resources.
  4. For Catalogs, choose <account_id>:s3tablescatalog/tbacblog-customer-bucket and <account_id>:salescatalog/dev.
  5. In the Catalog permissions section, choose Describe for permissions.
  6. Choose Grant.

Grant permission to the DataAnalyst role for the sales domain and non-sensitive data

Bob as DataSteward completes the following steps to grant permission to the DataAnalyst role (Charlie) for the sales domain for non-sensitive data:

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the DataAnalyst role.
  3. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and provide the following values:
    1. Key: Domain and Value: sales
    2. Key: Sensitivity and Value: false

  4. In the Database permissions section, choose Describe for permissions.
  5. In the Table permissions section, select Select and Describe for permissions.
  6. Choose Grant.

Grant permission to the BIEngineer role for sales domain data

Bob as DataSteward completes the following steps to grant permission to the BIEngineer role (Doug) for all sales domain data:

  1. In the navigation pane, choose Datalake permissions, then choose Grant.
  2. In the Principals section, for IAM users and roles, choose the BIEngineer role.
  3. In the LF-Tags or catalog resources section, select Resources matched by LF-Tags and provide the following values:
    1. Key: Domain and Value: sales
  4. In the Database permissions section, choose Describe for permissions.
  5. In the Table permissions section, select Select and Describe for permissions.
  6. Choose Grant.

This completes the steps to grant S3 Tables and Redshift federated tables permissions to various data personas using LF-TBAC.

Verify data access

In this step, we log in as individual data personas and query the lakehouse tables that are available to each persona.

Use Athena to analyze customer information as the DataAnalyst role

Charlie signs in to the Athena console as the DataAnalyst role. He runs the following sample SQL query:

SELECT * FROM
"redshift_salescatalog/dev"."sales"."store_sales" s
JOIN
"s3tablescatalog/tbacblog-customer-bucket"."tbacblog_namespace"."customer" c 
ON c.c_customer_sk = s.customer_sk
LIMIT 5;

Run a sample query to access the 4 columns in the S3table customer that DataAnalyst does not have access to. You should receive an error as shown in the screenshot. This verifies column level fine grained access using LF-tags on the lakehouse tables.

Use the Redshift query editor to analyze customer data as the DataAnalyst role

Charlie signs in to the Redshift query editor v2 as the DataAnalyst role and runs the following sample SQL query:

SELECT * FROM
"dev@redshift_salescatalog"."sales"."store_sales" s
JOIN
"tbacblog-customer-bucket@s3tablescatalog"."tbacblog_namespace"."customer" c 
ON c.c_customer_sk = s.customer_sk
LIMIT 5;

This verifies the DataAnalyst access to the lakehouse tables with LF-tags based permissions, using Redshift Spectrum

Use Amazon EMR to process customer data as the BIEngineer role

Doug uses Amazon EMR to process customer data with the BIEngineer role:

  1. Sign-in to the EMR Studio as Doug, with BIEngineer role. Ensure EMR Serverless application is attached to the workspace with BIEngineer as the EMR runtime role.
    Download the PySpark notebook tbacblog_emrs.ipynb. Upload to your studio environment.
  2. Change the account id, AWS Region and resource names as per your setup. Restart kernel and clear output.
  3. Once your pySpark kernel is ready, run the cells and verify access.This verifies access using LF-tags to the lakehouse tables as the EMR runtime role. For demonstration, we are also providing the pySpark script tbacblog_sparkscript.py that you can run as EMR batch job and Glue 5.0 ETL.

Doug has also set up Amazon SageMaker Unified Studio as covered in the blog post Accelerate your analytics with Amazon S3 Tables and Amazon SageMaker Lakehouse. Doug logs in to SageMaker Unified Studio and select previously created project to perform his analysis. He navigates to the Build options and choose JupyterLab under IDE & Applications. He uses the downloaded pyspark notebook and updates it as per his Spark query requirements. He then runs the cells by selecting compute as project.spark.fineGrained.

Doug can now start using Spark SQL and start processing data as per fine grained access controlled by the Tags.

Clean up

Complete the following steps to delete the resources you created to avoid unexpected costs:

  1. Delete the Redshift Serverless workgroups.
  2. Delete the Redshift Serverless associated namespace.
  3. Delete the EMR Studio and EMR Serverless instance.
  4. Delete the AWS Glue catalogs, databases, and tables and Lake Formation permissions.
  5. Delete the S3 Tables bucket.
  6. Empty and delete the S3 bucket.
  7. Delete the IAM roles created for this post.

Conclusion

In this post, we demonstrated how you can use Lake Formation tag-based access control with the SageMaker lakehouse architecture to achieve unified and scalable permissions to your data warehouse and data lake. Now administrators can add access permissions to federated catalogs using attributes and tags, creating automated policy enforcement that scales naturally as new assets are added to the system. This eliminates the operational overhead of manual policy updates. You can use this model for sharing resources across accounts and Regions to facilitate data sharing within and across enterprises.

We encourage AWS data lake customers to try this feature and share your feedback in the comments. To learn more about tag-based access control, visit the Lake Formation documentation.

Acknowledgment: A special thanks to everyone who contributed to the development and launch of TBAC: Joey Ghirardelli, Xinchi Li, Keshav Murthy Ramachandra, Noella Jiang, Purvaja Narayanaswamy, Sandya Krishnanand.


About the Authors

Sandeep Adwankar is a Senior Product Manager with Amazon SageMaker Lakehouse . Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that help customers improve how they manage, secure, and access data.

Srividya Parthasarathy is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Aarthi Srinivasan is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with AWS customers and partners to architect lakehouse solutions, enhance product features, and establish best practices for data governance.

Improve Amazon EMR HBase availability and tail latency using generational ZGC

Post Syndicated from Vishal Chaudhary original https://aws.amazon.com/blogs/big-data/improve-amazon-emr-hbase-availability-and-tail-latency-using-generational-zgc/

At Amazon EMR, we constantly listen to our customers’ challenges with running large-scale Amazon EMR HBase deployments. One consistent pain point that kept emerging is unpredictable application behavior due to garbage collection (GC) pauses on HBase. Customers running critical workloads on HBase were experiencing occasional latency spikes due to varying GC pauses, particularly impacting when they occurred during peak business hours.

To reduce this unpredictable impact to business-critical applications running on HBase, we turn to Oracle’s Z Garbage Collector (ZGC), specifically it’s generational support introduced in JDK 21. Generational ZGC delivers consistent sub-millisecond pause times that dramatically reduce tail latency.

In this post, we examine how unpredictable GC pauses affect business-critical workloads, benefits of enabling generational ZGC in HBase. We also cover additional GC tuning techniques to improve the application throughput and reduce tail latency. Amazon EMR 7.10.0 introduces new configuration parameters that allow you to seamlessly configure and tune the garbage collector for HBase RegionServers.

By incorporating generational collection into ZGC’s ultra-low pause architecture, it efficiently handles both short-lived and long-lived objects, making it exceptionally well-suited to HBase’s workload characteristics:

  • Handling mixed object lifetimes – HBase operations create a mix of short-lived objects (such as temporary buffers for read/write operations) and long-lived objects (such as cached data blocks and metadata). Generational ZGC can efficiently manage both, reducing overall GC frequency and impact.
  • Adapting to workload patterns – As workload patterns change throughout the day — for instance, from write-heavy ingestion to read-heavy analytics — generational ZGC adapts its collection strategy, maintaining optimal performance.
  • Scaling with heap size – As data volumes grow and HBase clusters require larger heaps, generational ZGC maintains it’s sub-millisecond pause times, providing consistent performance even as you scale up.

Understanding the impact of GC pauses on HBase

When running HBase RegionServers, the JVM heap can accumulate a large number of objects, both short-lived (temporary objects created during operations) and long-lived (cached data, metadata). Traditional garbage collectors like Garbage-First Garbage Collector (G1 GC) need to pause application threads during certain phases of garbage collection, particularly during “stop-the-world” (STW) events. GC pauses can have several impacts on HBase :

  • Latency spikes – GC pauses introduce latency spikes, often impacting tail latencies (p99.9 and p99.99) of the application which can lead to timeout for client requests and inconsistent response times..
  • Application availability – All application threads are halted during STW events and it negatively impacts overall application availability.
  • RegionServer failures – If GC pauses exceed the configured ZooKeeper session timeout, they might lead to RegionServer failures.

HBase RegionServer reports whenever there is an unusually long GC pause time using the JvmPauseMonitor. The following log entry shows an example of GC pauses reported by HBase RegionServer. During YCSB benchmarking, G1 GC exhibited 75 such pauses over a 7-hour period, whereas generational ZGC showed no long pauses under identical workload and testing conditions.

INFO  [JvmPauseMonitor] util.JvmPauseMonitor: Detected pause in JVM or host machine (eg GC): pause of approximately 2839ms
INFO  [JvmPauseMonitor] util.JvmPauseMonitor: Detected pause in JVM or host machine (eg GC): pause of approximately 3021ms

G1 GC pauses are proportional to the pressure on the heap and the object allocation patterns. As a result, the pauses might get worse if the heap is under too much load, whereas generational ZGC maintains it’s pause times goals even under high pressure.

Pause time and availability (uptime) comparison: Generational ZGC vs. G1GC in Amazon EMR HBase

Our testing revealed significant differences in GC pause time between the generational ZGC and G1 GC for HBase on Amazon EMR 7.10. We used 1 m5.4xlarge (primary), 5 m5.4xlarge (core) nodes cluster settings and ran multiple iterations of 1-billion rows YCSB workloads to compare the GC pauses and uptime percentage. Based on our test cluster, we observed a GC pause time improvement from over 1 minute, 24 seconds, to under 1 seconds for over an hour-long execution, improving the application uptime from 98.08% to 99.99%.

We conducted extensive performance testing comparing G1 GC and generational ZGC on HBase clusters running on Amazon EMR, using the default heap settings automatically configured based on Amazon Elastic Compute Cloud (Amazon EC2) instance type. The following image shows the comparison in both GC pause time and uptime percentage at a peak load of 3,00,000 requests per second (data sampled over 1 hour).

Side-by-side comparison of Java garbage collectors showing Generational ZGC's superior pause time and uptime metrics versus G1GC

The following figures show the breakdown of the 1-hour runtime in 10-minute intervals. The left vertical axis measures the uptime, the right vertical axis measures the GC pause time, and the horizontal axis shows the interval. The generational ZGC maintained consistent uptime and pause time in milliseconds, and G1 GC demonstrated inconsistent and decreased uptime, pause times in seconds.

G1GC performance chart with dual y-axes: uptime percentage bars declining from 99.72% to 99.31%, and pause time trend peaking at 14.6s

Generational ZGC performance visualization with consistent uptime above 99.98% and fluctuating pause times peaking at 93ms

Tail latency comparison: Generational ZGC vs. G1GC in Amazon EMR HBase

One of the most compelling advantages of generational ZGC over G1 GC is its predictable garbage collection behavior and the impact on application tail latency. G1 GC’s collection triggers are non-deterministic, meaning pause times can vary significantly and occur at unpredictable intervals. These unexpected pauses, though generally manageable, can create latency spikes that particularly affect the slowest percentile of operations. In contrast, generational ZGC maintains consistent, sub-millisecond pause times throughout its operation. This predictability proves crucial for applications requiring stable performance, especially at the highest percentiles of latency (99.9th and 99.99th percentiles). Our YCSB benchmark testing reveals the real-world impact of these different approaches. The following graph illustrates tail latency distribution between G1 GC and generational ZGC over a 2-hour sampling period :

Dual violin plot visualization comparing garbage collector latency distributions, demonstrating Generational ZGC's superior performance with lower mean latencies and tighter distribution

Improvements to BucketCache

BucketCache is an off-heap cache in HBase that is used to cache the frequently accessed data blocks and minimize disk I/O. Bucket cache and heap memory works in conjunction and might increase the contention on the heap depending on the workload. Generational ZGC maintains it’s pause time goals even with a terabyte-sized bucket cache. We benchmarked multiple HBase clusters with varying bucket cache sizes and 32 GB RegionServer heap. The following figures show the peak pause times observed over a 1-hour sampling period, comparing G1 GC and generational ZGC performance.

128GB Bucket Cache performance metrics displaying Generational ZGC's superior pause times and uptime compared to G1GC implementation

Side-by-side performance metrics showing Generational ZGC's 1.1s pause time and 99.97% uptime versus G1GC's longer pauses and lower uptime

Enabling this feature and additional fine-tuning parameters

To enable this feature, follow the configurations mentioned in the Performance Considerations. In the following sections, we discuss additional fine-tuning parameters to tailor the configuration for your specific use case.

Fixed JVM heap 

Batch processing jobs and short-lived applications benefit from dynamic allocation’s ability to adapt to varying input sizes and processing demands when multiple applications co-exist on the same cluster and run with resource constraints. The memory footprint can expand during peak processing and contract when the workload diminishes. However, for production HBase deployments without any co-existing applications in the same fixed heap allocation offers stable, reliable performance.

Dynamic heap allocation is when the JVM flexibly grows and shrinks its memory usage between minimum (-Xms) and maximum (-Xmx) limits based on application needs, returning unused memory to the operating system. However, this flexibility comes at the cost of performance overhead and memory fragmentation. Dynamic allocation seemed flexible, but it created constant disruptions. The JVM was always negotiating with the operating system for memory, leading to performance overhead and fragmentation. On the other hand, fixed heap allocation pre-allocates a constant amount of memory for the JVM at startup and maintains it throughout runtime, providing better performance by reducing memory negotiation overhead with the operating system. To enable this feature, use the following configuration: :

[
    {
        "Classification": "hbase",
        "Properties": {
            "hbase.regionserver.fixed.heap.enabled": "true"
        }
    }
]

Enable pre-touch

Applications with large heaps can experience more significant pauses when the JVM needs to allocate and fault in new memory pages. Pre-touch (-XX:+AlwaysPreTouch) instructs the JVM to physically touch and commit all memory pages during heap initialization, rather than waiting until they’re first accessed during runtime. This early commitment reduces the latency of on-demand page faults and memory mappings that occur when pages are first accessed, resulting in more predictable performance especially during heavy load situations. By pre-touching memory pages at startup, you trade a slightly longer JVM startup time for more consistent runtime performance. To enable pre-touch for your HBase cluster, use the following configuration :

[
    {
        "Classification": "hbase-env",
        "Properties": {},
        "Configurations": [
            {
                "Classification": "export",
                "Properties": {
                    "JAVA_HOME": "/usr/lib/jvm/jre-21",
                    "HBASE_REGIONSERVER_GC_OPTS": "\"-XX:+UseZGC -XX:+ZGenerational -XX:+AlwaysPreTouch\""
                }
            }
        ]
    }
]

Increasing memory mappings for large heaps

Depending on the workload and scale, you might need to increase the Java heap size to accommodate large data in memory. When using the generational ZGC with a large heap setup, it’s critical to also increase the operating system’s memory mapping limit (vm.max_map_count).

When a ZGC-enabled application starts, the JVM proactively checks the system’s vm.max_map_count value. If the limit is too low to support the configured heap, it will issue the following warning :

[warning] The system limit on number of memory mappings per process might be too low for the given
[warning] max Java heap size (131072M). Please adjust /proc/sys/vm/max_map_count to allow for at
[warning] least 235929 mappings (current limit is 65530). Continuing execution with the current
[warning] limit could lead to a premature OutOfMemoryError being thrown, due to failure to map memory.

To increase the memory mappings, use the following configuration and adjust the count value in the command based on the heap size of the application.

echo "vm.max_map_count = 262144" | sudo tee -a /etc/sysctl.conf
sudo sysctl -p

sudo systemctl restart hbase-regionserver

Conclusion

The introduction of generational ZGC and fixed heap allocation for HBase on Amazon EMR marks a significant leap forward in the predictable performance and tail latency reduction. By addressing the long-standing challenges of GC pauses and memory management, these features unlock new levels of efficiency and stability for Amazon EMR HBase deployments. Although the performance improvements vary depending on workload characteristics, you can expect to see significant enhancements in your Amazon EMR HBase clusters’ responsiveness and stability. As data volumes continue to grow and low-latency requirements become increasingly stringent, features like generational ZGC and fixed heap allocation become indispensable. We encourage HBase users on Amazon EMR to enable these features and experience the benefits firsthand. As always, we recommend testing in a staging environment that mirrors your production workload to fully understand the impact and optimize configurations for your specific use case.

Stay tuned for more innovations as we continue to push the boundaries of what’s possible with HBase on Amazon EMR.


About the authors

Vishal Chaudhary is a Software Development Engineer at Amazon EMR. His expertise is in Amazon EMR, HBase and Hive Query Engine. His dedication towards solving distributed system problems is helping Amazon EMR to achieve higher performance improvements.

Ramesh Kandasamy is an Engineering Manager at Amazon EMR. He is a long tenured Amazonian dedicated to solve distributed systems problems.

Enhance Amazon EMR observability with automated incident mitigation using Amazon Bedrock and Amazon Managed Grafana

Post Syndicated from Yu-Ting Su original https://aws.amazon.com/blogs/big-data/enhance-amazon-emr-observability-with-automated-incident-mitigation-using-amazon-bedrock-and-amazon-managed-grafana/

Maintaining high availability and quick incident response for Amazon EMR clusters is important in data analytics environments. In this post, we show you how to build an automated observability system that combines Amazon Managed Grafana with Amazon Bedrock to detect and remediate EMR cluster issues. We demonstrate how to integrate real-time monitoring with AI-powered remediation suggestions, combining Amazon Managed Grafana for visualization, Amazon Bedrock for intelligent response recommendations, and AWS Systems Manager for automated remediation actions on Amazon Web Services (AWS).

Solution overview

This solution helps you improve EMR cluster observability through a comprehensive four-layer architecture—comprising monitoring, notification, remediation, and knowledge management—to provide the following features:

  • Real-time monitoring of EMR clusters using Amazon Managed Service for Prometheus and Amazon Managed Grafana
  • Automated first-aid remediation through Systems Manager
  • AI-powered incident response suggestions using Amazon Bedrock
  • Integration with the AWS Premium Support knowledge base
  • Historical incident data archival and analysis

The implementation of this architecture delivers the following key benefit:

  • Reduced Mean time to resolution (MTTR)
  • Proactive incident prevention
  • Automated first-response actions
  • Knowledge base enrichment through machine learning

The following diagram illustrates the solution architecture.

End-to-end AWS monitoring solution diagram integrating Knowledge Center, Support, CloudWatch metrics with EventBridge rules and Lambda processing

The architecture comprises the following core components:

  • Monitoring layer – The monitoring layer uses Amazon Managed Service for Prometheus and Amazon CloudWatch to capture real-time metrics from EMR clusters. Amazon Managed Grafana serves as the visualization layer, offering comprehensive dashboards for Apache YARN, HDFS, Apache HBase, and Apache Hudi performance monitoring. Advanced alerting mechanisms trigger notifications based on predefined query results.
  • Notification layer – To provide timely and reliable alert delivery, the notification layer uses Amazon Simple Notification Service (Amazon SNS) for distribution and Amazon Simple Queue Service (Amazon SQS) for message queuing. This architecture prevents message delays and provides a robust trigger mechanism for AWS Lambda functions.
  • Remediation layer – The remediation layer enables automatic issue resolution through:
    • Lambda functions for orchestration
    • Systems Manager for script execution
    • Amazon Bedrock (amazon.nova-lite-v1:0) for generating intelligent response recommendations
  • Knowledge management layer – To maintain an up-to-date knowledge base, the solution:

We provide an AWS CloudFormation template to deploy the solution resources.

Prerequisites

Before starting this walkthrough, make sure you have access to the following AWS resources and configurations:

  • An AWS account
  • Access to the US East (N. Virginia) AWS Region
    • Add access to Amazon Bedrock foundation models (amazon.nova-lite-v1:0)

  • Amazon EMR version 6.15.0 (used in this demo)
  • Archived technical or troubleshooting articles
  • AWS IAM Identity Center enabled with at least one role that can become a Grafana administrator
  • (Optional) AWS Premium Support with a business support plan or higher for enhanced troubleshooting capabilities

Throughout this walkthrough, we provide detailed instructions to set up and configure these prerequisites if you haven’t already done so.

Configure resources using AWS CloudFormation

Complete the following steps to configure your resources:

  1. Launch the CloudFormation stack:

launch stack

  1. Provide emrobservability as the stack name.
  2. Select a virtual private cloud (VPC) and assign a public subnet.
  3. For EMRClusterName, enter a name for your cluster (default: emrObservability).
  4. Enter an existing Amazon S3 location as the Apache HBase root directory location (for example, s3://mybucket/my/hbase/rootdir/).
  5. For MasterInstanceType and CoreInstanceType, enter your instance types (default: m5.xlarge for both).
  6. For CoreInstanceCount, enter your instance count (default: 2).
  7. For SSHIPRange, use CheckIp and enter your IP (for example, 10.1.10/32).
  8. Choose the release label (default: 6.15.0).
  9. For KeyName, enter a key name to SSH to Amazon Elastic Compute Cloud (Amazon EC2) instances.
  10. For LatestAmiId, enter your AMI (default: /aws/service/ami-amazon-linux-latest/amzn2-ami-hvm-x86_64-gp2).
  11. For KBS3Bucket, enter a name for your S3 bucket (for example, mykbbucket).
  12. For SubscriptionEndpoint, enter an email address to receive notifications and responses (for example, [email protected]).

Accept subscription confirmation

Accept the subscription confirmation sent to the email address you specified in the CloudFormation stack parameters. The following screenshot shows an example of the email you receive.

AWS email confirmation for SNS topic subscription to QA Lambda function responses with opt-out instructions

Prepare the knowledge base

Complete the following steps to populate the S3 bucket with archived technical articles and cases:

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose the function CustomFunctionCopyKCArticlesToS3Bucket.

AWS Lambda console displaying Functions page with CustomFunctionCopyKCArticlesToS3Bucket function details

  1. Manually invoke the function by choosing Test on the Test tab.

AWS Lambda Test tab interface with event configuration options

  1. Verify successful execution by checking the CloudWatch logs.

AWS Lambda successful function execution result with null output

  1. Repeat the process for the Lambda function CustomFunctionCopyCasesToS3Bucket.

Lambda function interface displaying CustomFunctionCopyCasesToS3Bucket configuration with CloudFormation ID and description panel

AWS Lambda test interface showing Test event configuration options and action buttons

AWS Lambda function execution success message with null response and SHA-256 code

  1. Confirm the S3 bucket has been populated with archived technical articles and cases.

Amazon S3 bucket interface showing two folders with action buttons and search functionality

Sync data to the Amazon Bedrock knowledge base

Complete the following steps to sync the data to your knowledge base:

  1. On the Lambda console, choose Functions in the navigation pane.
  2. Choose the function KBDataSourceSync.

AWS Lambda console displaying filtered functions with CloudFormation tags, Python runtime versions, and modification timestamps

  1. Manually invoke the function by choosing Test on the Test tab.

This task might take 10–15 minutes to complete.

AWS Lambda console test configuration panel with CloudWatch integration and event creation controls

  1. Verify successful execution by checking the CloudWatch logs.

Lambda function execution results showing successful completion status and details

Configure your Amazon Managed Grafana workspace

Complete the following steps to configure your Amazon Managed Grafana workspace:

  1. On the Amazon Managed Grafana console, choose Workspaces in the navigation pane.
  2. Open your workspace.
  3. Choose Assign new user or group.

Amazon Grafana workspace showing IAM configuration notice and user assignment button

  1. Select your IAM Identity Center role and choose Assign users and groups.

Amazon Grafana IAM Identity Center user assignment panel with search and selection controls

  1. On the Admin dropdown menu, choose Make admin.

Amazon Grafana user list showing assigned viewer with admin action options

  1. Enable Grafana alerting, then choose Save changes.

Amazon Grafana alerting configuration panel showing disabled status with navigation tabs and edit button

Amazon Grafana configuration panel showing enabled alerting and plugin management settings

  1. Wait 10 minutes for the workspace to become active.
  2. When it’s active, sign in to the Grafana workspace. (For more information, refer to Connect to your workspace.)

Configure data sources

Add and configure the following data sources:

  1. For Service, choose CloudWatch, then select your Region and add CloudWatch as a data source.

  1. Choose Amazon Managed Service for Prometheus as a second data source and select your Region.

  1. Validate CloudWatch connectivity:
    1. Run test queries (for example, Namespace: AWS/EC2, Metric name: CPUUtilization, Statistic: Maximum).
      Amazon Managed Gragana interface showing CPU utilization query setup for EC2 instance.
    2. Verify CloudWatch metric retrieval.
      Line graph showing CPU utilization over time with peak at 40%.
  1. Validate Amazon Managed Service for Prometheus connectivity:
    1. Run test queries (for example, Metric: hadoop_hbase_numregionservers, Label filters: cluster_id = <Amazon EMR cluster ID>).
      Amazon Managed Grafana query interface showing Hadoop HBase metric configuration.
    2. Verify Prometheus metric retrieval.
      Amazon Managed Grafana monitoring dashboard showing a graph with HBase Region Server amount from 0 to 2

Confirm SNS notification channels

Complete the following steps to confirm your SNS notification is set up:

  1. On the Amazon SNS console, choose Topics in the navigation pane.
  2. Locate and note the ARNs for -LambdaFunctionTopic and -QALambdaFunctionTopic.

AWS SNS Topics list showing 4 topics with names, types, and ARNs

AWS SNS Topics console showing filtered search results for "LambdaFunctionTopic"

AWS SNS Topics console showing filtered search results for "QALambdaFunctionTopic"

  1. Choose Contact points under Alerting.

  1. Create the first contact point:
    1. For Name, enter SNS_SSM.
    2. For Integration, choose AWS SNS.
    3. For Topic, enter the ARN for LambdaFunctionTopic.
    4. For Auth Provider, choose Workspace IAM role.
    5. For Alert Message format, choose JSON.

  1. Create the second contact point:
    1. For Name, enter SNS_QA.
    2. For Integration, choose AWS SNS.
    3. For Topic, enter the ARN for QALambdaFunctionTopic.
    4. For Auth Provider, choose Workspace IAM role.
    5. For Alert Message format, choose JSON.

Create alert rules

Complete the following steps to set up two critical alert rules:

  1. Choose Alert rules under Alerting.

  1. Set up alerting if the Apache HBase region server status is abnormal:
    1. For Alert name, enter HBase region server down.
    2. For Data source, choose Amazon Managed Service for Prometheus.
    3. For Metric, choose hadoop_hbase_numregionservers.
      Alert rule configuration interface for HBase region server monitoring
    4. For Threshold, configure to alert if the region server count is less than 2 for 3 minutes.
      Amazon Managed Grafana alert rule configuration interface with expressions setup
    5. For Evaluation interval, set to 1 minute.
      New evaluation group creation modal showing P0_RegionServer name input and 1m interval settingHBase alert configuration panel showing P0_RegionServer group and 3m pending period
    6. For Contact point, choose SNS_SSM.
      Amazon Managed Grafana alert configuration interface showing labels and notifications setup with AWS SNS integration
  1. Create a second alert for if Amazon EC2 CPU utilization is abnormal:
    1. For Alert name, enter EC2 CPU utilization too high.
    2. For Data source, choose Amazon CloudWatch.
    3. For Namespace, choose AWS/EC2.
    4. For Metric name, choose CPUUtilization
    5. For Statistic, choose Maximum.
      Amazon CloudWatch query interface for setting up EC2 CPU utilization alert conditions
    6. For Threshold, configure to alert if CPU utilization is more than 95% for 3 minutes.
      Amazon Managed Grafana alert interface with Reduce and Threshold expressions for alert condition management
    7. For Evaluation interval, configure to 1 minute.
      New evaluation group configuration modal showing CPU utilization monitoring setup with 1-minute interval
      AWS Managed Grafana alert rule configuration screen showing evaluation behavior settings
    8. For Contact point, choose SNS_QA.Amazon Managed Grafana alert configuration showing customizable labels, contact point selection for SNS_QA integration
  1. On the alert rule creation page, scroll to 5. Add annotations and for Summary, add a clear description of the alert, for example, CPU utilization on EC2 instance is too high.

Alert configuration summary field with "CPU utilization on EC2 instance is too high" warning message

Apache HBase region server incident test

To confirm the system is working as expected, complete the following Apache HBase region server incident test:

  1. SSH into an EMR core instance.
  2. Stop the Apache HBase region server using systemctl:
 # Stop HBase region server service 
 sudo systemctl stop hbase-regionserver.service 

  1. Verify the service status:
 # Check the current state of HBase region server service 
 sudo systemctl status hbase-regionserver.service
  1. Observe Amazon Managed Grafana alert progression:
    1. Monitor alert status changes.
      Alert dashboard showing HBase region server alert status in pending state
      Alert dashboard showing HBase region server alert in firing state
    2. Verify SNS message generation.
    3. Confirm SQS message queuing.
    4. Track the Lambda function triggered for remediation.

Terminal output showing HBase RegionServer service status and daemon processes

HBase monitoring interface displaying region server status with health indicators and action buttons

CPU utilization stress test

Complete the following CPU utilization stress test:

  1. SSH into the EMR primary instance.
  2. Install stress testing tools:
 sudo amazon-linux-extras install epel -y
 sudo yum install stress -y 

  1. Verify the installation:
 stress --version 

  1. Generate high CPU load using the stress command and the following command structure:
 sudo stress [options] 

For our Amazon EMR test, use the following command:

 # For m5.xlarge instances (4 vCPUs) sudo stress --cpu 4 

-c 4 in the command creates 4 CPU-bound processes (one for each vCPU).The following are instance type vCPUs for your reference:

  • m5.xlarge: 4 vCPUs
  • m5.2xlarge: 8 vCPUs
  • m5.4xlarge: 16 vCPUs
  1. Monitor system response:
    1. Observe Amazon Managed Grafana alert status changes.
      Amazon Managed Grafana dashboard header showing rules status
    2. Verify Amazon Bedrock recommendation generation.
    3. Check SNS email notification delivery.
      AWS SNS notification email showing troubleshooting steps for high CPU usageCode snippet showing CPU usage troubleshooting steps in red text

Best practices and considerations

Monitoring infrastructure requires precise alert prioritization and threshold configuration. Alert aggregation techniques prevent notification overload by consolidating event streams and reducing redundant alerts. Operational teams must maintain dashboards through consistent updates and metric integration, providing real-time visibility into system performance and health.

Security implementations focus on least-privilege AWS Identity and Access Management (IAM) roles, restricting access to critical resources and minimizing potential breach vectors. Data protection strategies involve encryption protocols for information at rest and in transit, using AES-256 standards. Automated security audit processes scan automation scripts, identifying potential vulnerabilities through code analysis and runtime inspection.

Performance optimization in serverless architectures uses Lambda extensions to cache knowledge base content, reducing latency and improving response times. Retry mechanisms for API calls implement exponential backoff strategies, mitigating transient network exceptions and enhancing system resilience. Execution time monitoring of Lambda functions enables detection of anomalies through statistical analysis, providing insights into potential system-wide incidents or performance degradations.

Clean up

To avoid incurring future charges, delete the resources by deleting the parent stack on the AWS CloudFormation console.

Conclusion

This solution provides a robust framework for automated EMR cluster monitoring and incident response. By combining real-time monitoring with AI-powered remediation suggestions and automated execution, organizations can significantly reduce MTTR for common Amazon EMR issues while building a knowledge base for future incident response.

Try out this solution for your own use case, and leave your feedback in the comments section.


About the authors

Author Yu-ting Su, Sr. Hadoop System Engineer, AWS Support Engineering. Yu-Ting is a Sr. Hadoop Systems Engineer at Amazon Web Services (AWS). Her expertise is in Amazon EMR and Amazon OpenSearch Service. She’s passionate about distributing computation and helping people to bring their ideas to life.

Stream data from Amazon MSK to Apache Iceberg tables in Amazon S3 and Amazon S3 Tables using Amazon Data Firehose

Post Syndicated from Pratik Patel original https://aws.amazon.com/blogs/big-data/stream-data-from-amazon-msk-to-apache-iceberg-tables-in-amazon-s3-and-amazon-s3-tables-using-amazon-data-firehose/

In today’s data-driven/fast-paced landscape/environment real-time streaming analytics has become critical for business success. From detecting fraudulent transactions in financial services to monitoring Internet of Things (IoT) sensor data in manufacturing, or tracking user behavior in ecommerce platforms, streaming analytics enables organizations to make split-second decisions and respond to opportunities and threats as they emerge.

Increasingly, organizations are adopting Apache Iceberg, an open source table format that simplifies data processing on large datasets stored in data lakes. Iceberg brings SQL-like familiarity to big data, offering capabilities such as ACID transactions, row-level operations, partition evolution, data versioning, incremental processing, and advanced query scanning. It seamlessly integrates with popular open source big data processing frameworks Apache Spark, Apache Hive, Apache Flink, Presto, and Trino. Amazon Simple Storage Service (Amazon S3) supports Iceberg tables both directly using the Iceberg table format and in Amazon S3 Tables.

Although Amazon Managed Streaming for Apache Kafka (Amazon MSK) provides robust, scalable streaming capabilities for real-time data needs, many customers need to efficiently and seamlessly deliver their streaming data from Amazon MSK to Iceberg tables in Amazon S3 and S3 Tables. This is where Amazon Data Firehose (Firehose) comes in. With its built-in support for Iceberg tables in Amazon S3 and S3 Tables, Firehose makes it possible to seamlessly deliver streaming data from provisioned MSK clusters to Iceberg tables in Amazon S3 and S3 Tables.

As a fully managed extract, transform, and load (ETL) service, Firehose reads data from your Apache Kafka topics, transforms the records, and writes them directly to Iceberg tables in your data lake in Amazon S3. This new capability requires no code or infrastructure management on your part, allowing for continuous, efficient data loading from Amazon MSK to Iceberg in Amazon S3.In this post, we walk through two solutions that demonstrate how to stream data from your Amazon MSK provisioned cluster to Iceberg-based data lakes in Amazon S3 using Firehose.

Solution 1 overview: Amazon MSK to Iceberg tables in Amazon S3

The following diagram illustrates the high-level architecture to deliver streaming messages from Amazon MSK to Iceberg tables in Amazon S3.

bdb-4769-image-1

Prerequisites

To follow the tutorial in this post, you need the following prerequisites:

Verify permission

Before configuring the Firehose delivery stream, you must verify the destination table available in the Data Catalog.

  1. On the AWS Glue console, go to Glue Data Catalog and verify the Iceberg table is available with the required attributes.

bdb-4769-image-2

  1. Verify your Amazon MSK provisioned cluster is up and running with IAM authentication, and multi-VPC connectivity is enabled for it.

bdb-4769-image-3

  1. Grant Firehose access to your private MSK cluster:
    1. On the Amazon MSK console, go to the cluster and choose Properties and Security settings.
    2. Edit the cluster policy and define a policy similar to the following example:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Principal": {
        "Service": [
          "firehose.amazonaws.com"
        ]
    },
    "Effect": "Allow",
    "Action": [
      "kafka:CreateVpcConnection"
    ],
    "Resource": "<Amazon MSK cluster-arn>"
    }
  ]
}

This ensures Firehose has the necessary permissions on the source Amazon MSK provisioned cluster.

Create a Firehose role

This section describes the permissions that grant Firehose access to ingest, process, and deliver data from source to destination. You must specify an IAM role that grants Firehose permissions to ingest source data from the specified Amazon MSK provisioned cluster. Make sure that the following trust policies are attached to that role so that Firehose can assume it:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Principal": {
        "Service": [
          "firehose.amazonaws.com"
        ]
      },
      "Effect": "Allow",
      "Action": "sts:AssumeRole"
    }
  ]
}

Make sure that this role grants Firehose the following permissions to ingest source data from the specified Amazon MSK provisioned cluster:

{
   "Version": "2012-10-17",      
   "Statement": [{
        "Effect":"Allow",
        "Action": [
           "kafka:GetBootstrapBrokers",
           "kafka:DescribeCluster",
           "kafka:DescribeClusterV2",
           "kafka-cluster:Connect"
         ],
         "Resource": "<CLUSTER-ARN>"
       },
       {
         "Effect":"Allow",
         "Action": [
           "kafka-cluster:DescribeTopic",
           "kafka-cluster:DescribeTopicDynamicConfiguration",
           "kafka-cluster:ReadData"
         ],
         "Resource": "<TOPIC-ARN>"
       }]
}

Make sure the Firehose role has permissions to the Glue Data Catalog and S3 bucket:

{
    "Version": "2012-10-17",  
    "Statement":
    [    
        {      
            "Effect": "Allow",      
            "Action": [
                "glue:GetTable",
                "glue:GetDatabase",
                "glue:UpdateTable"
            ],      
            "Resource": [   
                "arn:aws:glue:<region>:<aws-account-id>:catalog",
                "arn:aws:glue:<region>:<aws-account-id>:database/*",
                "arn:aws:glue:<region>:<aws-account-id>:table/*/*"             
            ]    
        },        
        {      
            "Effect": "Allow",      
            "Action": [
                "s3:AbortMultipartUpload",
                "s3:GetBucketLocation",
                "s3:GetObject",
                "s3:ListBucket",
                "s3:ListBucketMultipartUploads",
                "s3:PutObject",
                "s3:DeleteObject"
            ],      
            "Resource": [   
                "arn:aws:s3:::<S3 bucket name>",
                "arn:aws:s3:::<S3 bucket name>/*"              
            ]    
        } 
    ]
}    

For detailed policies, refer to the following resources:

Now you have verified that your source MSK cluster and destination Iceberg table are available, you’re ready to set up Firehose to deliver streaming data to the Iceberg tables in Amazon S3.

Create a Firehose stream

Complete the following steps to create a Firehose stream:

  1. On the Firehose console, choose Create Firehose stream.
  2. Choose Amazon MSK for Source and Apache Iceberg Tables for Destination.

bdb-4769-image-4

  1. Provide a Firehose stream name and specify the cluster configurations.

bdb-4769-image-5

  1. You can choose an MSK cluster in the current account or another account.
  2. To choose the cluster, it must be in active state with IAM as one of its access control methods and multi-VPC connectivity should be enabled.

bdb-4769-image-6

  1. Provide the MSK topic name from which Firehose will read the data.

bdb-4769-image-7

  1. Enter the Firehose stream name.

bdb-4769-image-8

  1. Enter the destination settings where you can opt to send data in the current account or across accounts.
  2. Select the account location as Current account, choose an appropriate AWS Region, and for Catalog, choose the current account ID.

bdb-4769-image-9

To route streaming data to different Iceberg tables and perform operations such as insert, update, and delete, you can use Firehose JQ expressions. You can find the required information here.

  1. Provide the unique key configuration, which makes it possible to perform update and delete actions on your data.

bdb-4769-image-10

  1. Go to Buffer hints and configure Buffer size to 1 MiB and Buffer interval to 60 seconds. You can tune these settings according to your use case needs.
  2. Configure your backup settings by providing an S3 backup bucket.

With Firehose, you can configure backup settings by specifying an S3 backup bucket with custom prefixes like error, so failed records are automatically preserved and accessible for troubleshooting and reprocessing.

bdb-4769-image-11

  1. Under Advanced settings, enable Amazon CloudWatch error logging.

bdb-4769-image-12

  1. Under Service access, choose the IAM role you created earlier for Firehose.
  2. Verify your configurations and choose Create Firehose stream.

bdb-4769-image-14

The Firehose stream will be available and it will stream data from the MSK topic to the Iceberg table in Amazon S3.

bdb-4769-image-15

You can query the table with Amazon Athena to validate the streaming data.

  1. On the Athena console, open the query editor.
  2. Choose the Iceberg table and run a table preview.

You will be able to access the streaming data in the table.

bdb-4769-image-16

Solution 2 overview: Amazon MSK to S3 Tables

S3 Tables is built on Iceberg’s open table format, providing table-like capabilities directly to Amazon S3. You can organize and query data using familiar table semantics while using Iceberg’s features for schema evolution, partition evolution, and time travel capabilities. The feature performs ACID-compliant transactions and supports INSERT, UPDATE, and DELETE operations in Amazon S3 data, making data lake management more efficient and reliable.

You can use Firehose to deliver streaming data from an Amazon MSK provisioned cluster to Iceberg tables in Amazon S3. You can create an S3 table bucket using the Amazon S3 console, and it registers the bucket to AWS Lake Formation, which helps you manage fine-grained access control for your Iceberg-based data lake on S3 Tables. The following diagram illustrates the solution architecture.

Prerequisites

You should have the following prerequisites:

  • An AWS account
  • An active Amazon MSK provisioned cluster with IAM access control authentication enabled and multi-VPC connectivity
  • The Firehose role mentioned earlier with the additional IAM policy:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "Statement1",
            "Effect": "Allow",
            "Action": [
                "lakeformation:GetDataAccess"
            ],
            "Resource": [
                "*"
            ]
        }
    ]
}

Further, in your Firehose role, add s3tablescatalog as a resource to provide access to S3 Table as shown below.

Create an S3 table bucket

To create an S3 table bucket on the Amazon S3 console, refer to Creating a table bucket.

When you create your first table bucket with the Enable integration option, Amazon S3 attempts to automatically integrate your table bucket with AWS analytics services. This integration makes it possible to use AWS analytics services to query all tables in the current Region. This is an important step for the further set up. If this integration is already in place, you can use the AWS Command Line Interface (AWS CLI) as follows:

aws s3tables create-table-bucket --region <region id> --name <bucket name>

bdb-4769-image-18

Create a namespace

An S3 table namespace is a logical construct within an S3 table bucket. Each table belongs to a single namespace. Before creating a table, you must create a namespace to group tables under. You can create a namespace by using the Amazon S3 REST API, AWS SDK, AWS CLI, or integrated query engines.

You can use the following AWS CLI to create a table namespace:

aws s3tables create-namespace --table-bucket-arn arn:aws:s3tables:us-east-1:111122223333:bucket/amzn-s3-demo-bucket --namespace example_namespace

Create a table

An S3 table is a sub-resource of a table bucket. This resource stores S3 tables in Iceberg format so you can work with them using query engines and other applications that support Iceberg. You can create a table with the following AWS CLI command:

aws s3tables create-table --cli-input-json file://mytabledefinition.json

The following code is for mytabledefinition.json:

{
    "tableBucketARN": "arn:aws:s3tables:us-east-1:111122223333:bucket/amzn-s3-demo-table-bucket",
    "namespace": "example_namespace ",
    "name": "example_table",
    "format": "ICEBERG",
    "metadata": {
        "iceberg": {
            "schema": {
                "fields": [
                     {"name": "id", "type": "int", "required": true},
                     {"name": "name", "type": "string"},
                     {"name": "value", "type": "int"}
                ]
            }
        }
    }
}

Now you have the required table with the relevant attributes available in Lake Formation.

Grant Lake Formation permissions on your table resources

After integration, Lake Formation manages access to your table resources. It uses its own permissions model (Lake Formation permissions) that enables fine-grained access control for Glue Data Catalog resources. To allow Firehose to write data to S3 Tables, you can grant a principal Lake Formation permission on a table in the S3 table bucket, either through the Lake Formation console or AWS CLI. Complete the following steps:

  1. Make sure you’re running AWS CLI commands as a data lake administrator. For more information, see Create a data lake administrator.
  2. Run the following command to grant Lake Formation permissions on the table in the S3 table bucket to an IAM principal (Firehose role) to access the table:
aws lakeformation grant-permissions \
--region <region e.g. us-east-1> \
--cli-input-json \
'{
    "Principal": {
        "DataLakePrincipalIdentifier": "<Amazon Data Firehose role ARN e.g. arn:aws:iam::<accound-id>:role/ExampleRole>"
    },
    "Resource": {
        "Table": {
            "CatalogId": "<account-id>:<s3tablescatalog>/<S3 table bucket name>",
            "DatabaseName": "<S3 table bucket namespace e.g. test_namespace>",
            "Name": "<S3 table bucket table name e.g. test_table>"
        }
    },
    "Permissions": [
        "ALL"
    ]
}'

Set up a Firehose stream to S3 Tables

To set up a Firehose stream to S3 Tables using the Firehose console, complete the following steps:

  1. On the Firehose console, choose Create Firehose stream.
  2. For Source, choose Amazon MSK.
  3. For Destination, choose Apache Iceberg Tables.
  4. Enter a Firehose stream name.
  5. Configure your source settings.
  6. For Destination settings, select Current Account, choose your Region, and enter the name of the table bucket you want to stream in.
  7. Configure the database and table names using Unique Key configuration settings, JSONQuery expressions, or in an AWS Lambda function.

For more information, refer to Route incoming records to a single Iceberg table and Route incoming records to different Iceberg tables.

  1. Under Backup settings, specify a S3 backup bucket.
  2. For Existing IAM roles under Advanced settings, choose the IAM role you created for Firehose.
  3. Choose Create Firehose stream.

The Firehose stream will be available and it will stream data from the Amazon MSK topic to the Iceberg table. You can verify it by querying the Iceberg table using an Athena query.

bdb-4769-image-19

Clean up

It’s always a good practice to clean up the resources created as part of this post to avoid additional costs. To clean up your resources, delete the MSK cluster, Firehose stream, Iceberg S3 table bucket, S3 general purpose bucket, and CloudWatch logs.

Conclusion

In this post, we demonstrated two approaches for data streaming from Amazon MSK to data lakes using Firehose: direct streaming to Iceberg tables in Amazon S3, and streaming to S3 Tables. Firehose alleviates the complexity of traditional data pipeline management by offering a fully managed, no-code approach that handles data transformation, compression, and error handling automatically. The seamless integration between Amazon MSK, Firehose, and Iceberg format in Amazon S3 demonstrates AWS’s commitment to simplifying big data architectures while maintaining the robust features of ACID compliance and advanced query capabilities that modern data lakes demand. We hope you found this post helpful and encourage you to try out this solution and simplify your streaming data pipelines to Iceberg tables.


About the authors

bdb-4769-image-21Pratik Patel is Sr. Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively keep customers’ AWS environments operationally healthy.

Amar is a seasoned Data Analytics specialist at AWS UK, who helps AWS customers to deliver large-scale data solutions. With deep expertise in AWS analytics and machine learning services, he enables organizations to drive data-driven transformation and innovation. He is passionate about building high-impact solutions and actively engages with the tech community to share knowledge and best practices in data analytics.

bdb-4769-image-22Priyanka Chaudhary is a Senior Solutions Architect and data analytics specialist. She works with AWS customers as their trusted advisor, providing technical guidance and support in building Well-Architected, innovative industry solutions.

Build a secure serverless streaming pipeline with Amazon MSK Serverless, Amazon EMR Serverless and IAM

Post Syndicated from Shubham Purwar original https://aws.amazon.com/blogs/big-data/build-a-secure-serverless-streaming-pipeline-with-amazon-msk-serverless-amazon-emr-serverless-and-iam/

The exponential growth and vast volume of streaming data have made it a vital resource for organizations worldwide. To unlock its full potential, real-time analytics are essential for extracting actionable insights. Derived from a wide range of sources, including social media, Internet of Things (IoT) sensors, and user interactions, streaming data empowers businesses to respond promptly to emerging trends and events, make informed decisions, and stay ahead of the competition.

Commonly streaming applications use Apache Kafka for data ingestion and Apache Spark Structured Streaming for processing. However, integrating and securing these components poses considerable challenges for users. The complexity of managing certificates, keystores, and TLS configurations to connect Spark Streaming to Kafka brokers demands specialized expertise. A managed, serverless framework would greatly simplify this process, alleviating the need for manual configuration and streamlining the integration of these critical components.

To simplify the management and security of traditional streaming architectures, you can use Amazon Managed Streaming for Apache Kafka (Amazon MSK). This fully managed service simplifies data ingestion and processing. Amazon MSK Serverless alleviates the need for cluster management and scaling, and further enhances security by integrating AWS Identity and Access Management (IAM) for authentication and authorization. This consolidated approach replaces complex certificate and key management require by TLS client authentication through AWS Certificate Manager, streamlining operations and bolstering data protection. For instance, when a client attempts to write data to the cluster, MSK Serverless verifies both the client’s identity and its permissions using IAM.

For efficient data processing, you can use Amazon EMR Serverless with a Spark application built on the Spark Structured Streaming framework, enabling near real-time data processing. This setup seamlessly handles large volumes of data from MSK Serverless, using IAM authentication for secure and swift data processing.

The post demonstrates a comprehensive, end-to-end solution for processing data from MSK Serverless using an EMR Serverless Spark Streaming job, secured with IAM authentication. Additionally, it demonstrates how to query the processed data using Amazon Athena, providing a seamless and integrated workflow for data processing and analysis. This solution enables near real-time querying of the latest data processed from MSK Serverless and EMR Serverless using Athena, providing instant insights and analytics.

Solution overview

The following diagram illustrates the architecture that you implement through this post.

The workflow consists of the following steps:

  1. The architecture begins with an MSK Serverless cluster set up with IAM authentication. An Amazon Elastic Compute Cloud (Amazon EC2) instance runs a Python script producer.py that acts as a data producer, sending sample data to a Kafka topic within the cluster.
  2. The Spark Streaming job retrieves data from the Kafka topic, stores it in Amazon Simple Storage Service (Amazon S3), and creates a corresponding table in the AWS Glue Data Catalog. As it continuously consumes data from the Kafka topic, the job stays up-to-date with the latest streaming data. With checkpointing enabled, the job tracks processed records, allowing it to resume from where it left off in case of a failure, providing seamless data processing.
  3. To analyze this data, users can use Athena, a serverless query service. Athena enables interactive SQL-based exploration of data directly in Amazon S3 without the need for complex infrastructure management.

Prerequisites

Before getting started, make sure you have the following:

  • An active AWS account with billing enabled
  • An IAM user with administrator access (AdministratorAccess policy) or specific permissions to create and manage resources such as a virtual private cloud (VPC), subnet, security group, IAM roles, NAT gateway, internet gateway, EC2 client, MSK Serverless, EMR Serverless, Amazon EMR Studio, and S3 buckets
  • Sufficient VPC capacity in your chosen AWS Region

Although using an IAM user with administrator access will work, it’s recommended to follow the principle of least privilege in production environments by creating custom IAM policies with only the necessary permissions. The IAM user we create has the AdministrativeAccess policy attached to it. However, you might not need such elevated access.

For this post, we create the solution resources in the us-east-2 Region using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.

Create MSK Serverless and EMR Serverless resources

The vpc-msk-emr-serverless-studio.yaml stack creates a VPC, subnet, security group, IAM roles, NAT gateway, internet gateway, EC2 client, MSK Serverless, EMR Serverless, EMR Studio, and S3 buckets. To create the solution resources, complete the following steps:

  1. Launch the stack vpc-msk-emr-serverless-studio using the CloudFormation template:

  1. Provide the parameter values as listed in the following table.
Parameters Description Sample value
EnvironmentName An environment name that is prefixed to resource names. msk-emr-serverless-pipeline
InstanceType Amazon MSK client EC2 instance type. t2.micro
LatestAmiId Latest AMI ID of Amazon Linux 2023 for ec2 instance. You can use the default value. /aws/service/ami-amazon-linux-latest/al2023-ami-kernel-6.1-x86_64
VpcCIDR IP range (CIDR notation) for this VPC. 10.192.0.0/16
PublicSubnet1CIDR IP range (CIDR notation) for the public subnet in the first Availability Zone. 10.192.10.0/24
PublicSubnet2CIDR IP range (CIDR notation) for the public subnet in the second Availability Zone. 10.192.11.0/24
PrivateSubnet1CIDR IP range (CIDR notation) for the private subnet in the first Availability Zone. 10.192.20.0/24
PrivateSubnet2CIDR IP range (CIDR notation) for the private subnet in the second Availability Zone. 10.192.21.0/24

The stack creation process can take approximately 10 minutes to complete. You can check the Outputs tab for the stack after the stack is created.

Next, you set up the data ingestion to the Kafka topic from the Kafka EC2 instance.

Produce records to Kafka topic

Complete the following steps to set up data ingestion:

  1. On the Amazon EC2 console, go to the EC2 instance that you created using the CloudFormation template.

  1. Log in to the EC2 instance using Session Manager, a capability of AWS Systems Manager.
  2. Choose the instance msk-emr-serverless-blog and then choose Connect.

  1. Create a Kafka topic in MSK Serverless from the EC2 instance.
    1. In the following export command, replace my-endpoint with the MSKBootstrapServers value from the CloudFormation stack output:
      $ sudo su - ec2-user
      $ BS=<your-msk-serverless-endpoint (e.g.) boot-xxxxxx.yy.kafka-serverless.us-east-2.amazonaws.com:9098>

    2. Run the following command on the EC2 instance to create a topic called sales_data_topic:

Kafka client already installed at ec2-user home directory (/home/ec2-user) with MSK IAM Authentication jar and client configuration also created (/home/ec2-user/kafka_2.12-2.8.1/bin/client.properties) with IAM authentication properties.

The following code shows the contents of client.properties:

security.protocol=SASL_SSL
sasl.mechanism=AWS_MSK_IAM
sasl.jaas.config=software.amazon.msk.auth.iam.IAMLoginModule required;
sasl.client.callback.handler.class=software.amazon.msk.auth.iam.IAMClientCallbackHandler

/home/ec2-user/kafka_2.12-2.8.1/bin/kafka-topics.sh \
--bootstrap-server $BS \
--command-config /home/ec2-user/kafka_2.12-2.8.1/bin/client.properties \
--create --topic sales_data_topic \
--partitions 10

Created topic sales_data_topic.
  1. Run the following command to produce records to the Kafka topic using the syntheticSalesDataProducer.py Python script present in EC2 instance. Update the Region accordingly.
nohup python3 -u syntheticSalesDataProducer.py --num_records 1000 \
--sales_data_topic sales_data_topic --bootstrap_server $BS \
--region=us-east-2 > syntheticSalesDataProducer.log &

Understanding Amazon MSK IAM authentication with EMR Serverless

Amazon MSK IAM authentication enables secure authentication and authorization for Kafka clusters (MSK Serverless) using IAM roles. When integrating with EMR Serverless Spark Streaming, Amazon MSK IAM authentication allows Spark jobs to access Kafka topics securely, using IAM roles for fine-grained access control. This provides secure data processing and streaming.

IAM policy configuration

To enable EMR Serverless jobs to authenticate with an MSK Serverless cluster using IAM, you need to attach specific Kafka-related IAM permissions to the EMR Serverless job execution role. These permissions allow the job to perform essential operations on the Kafka cluster, topics, and consumer groups.The following IAM policy must be attached to the EMR Serverless job execution role to enable necessary permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "kafka-cluster:Connect",
                "kafka-cluster:DescribeCluster"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:cluster/<SERVERLESS_CLUSTER_NAME>/<ID>"
            ],
            "Effect": "Allow"
        },
        {
            "Action": [
                "kafka-cluster:CreateTopic",
                "kafka-cluster:DescribeTopic",
                "kafka-cluster:WriteData",
                "kafka-cluster:ReadData"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:topic/<SERVERLESS_CLUSTER_NAME>/*/*"
            ],
            "Effect": "Allow"
        },
        {
            "Action": [
                "kafka-cluster:AlterGroup",
                "kafka-cluster:DescribeGroup"
            ],
            "Resource": [
                "arn:aws:kafka:<AWS-REGION>:<ACCOUNTID>:group/<SERVERLESS_CLUSTER_NAME>/*/*"
            ],
            "Effect": "Allow"
        }
    ]
}

This code refers to the following actions:

  • Connect, DescribeCluster – Required to initiate a secure connection and obtain metadata
  • DescribeTopic, ReadData, WriteData – Enables data consumption and production
  • CreateTopic (optional) – Allows dynamic topic creation
  • AlterGroup, DescribeGroup – Needed for consumer group management in streaming jobs

These permissions make sure that the Spark Streaming job can securely authenticate and interact with MSK Serverless resources using its IAM role.

Required dependencies

To enable Amazon MSK IAM authentication in Spark (especially on EMR Serverless), specific JAR dependencies must be included in your Spark Streaming job using sparkSubmitParameters:

  • spark-sql-kafka-0-10_2.12 – This is the Kafka connector for Spark Structured Streaming. It provides the DataFrame API to read from and write to Kafka.
  • aws-msk-iam-auth – This JAR provides the IAM authentication mechanism required to connect to MSK Serverless using the AWS_MSK_IAM SASL mechanism.

You can include these dependencies directly by specifying them in the --packages argument when submitting the EMR Serverless job. For example:

--packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1,software.amazon.msk:aws-msk-iam-auth:2.2.0

When the job is submitted, EMR Serverless will automatically download these JARs from Maven Central (or another configured repository) at runtime. You don’t need to bundle them manually unless offline usage or specific versions are required.

Spark Streaming job configuration for Amazon MSK IAM authentication

In your Spark Streaming application, configure the Kafka source with SASL properties to enable IAM based authentication. The following code shows the relevant configuration:

topic_df = (spark.readStream
    .format("kafka")
    .option("kafka.bootstrap.servers", kafka_bootstrap_servers)
    .option("subscribe", topic_input)
    .option("startingOffsets", "earliest")
    .option("kafka.security.protocol","SASL_SSL")
    option("kafka.sasl.mechanism","AWS_MSK_IAM")
    .option("kafka.sasl.jaas.config","software.amazon.msk.auth.iam.IAMLoginModule required;")
    .option("kafka.sasl.client.callback.handler.class","software.amazon.msk.auth.iam.IAMClientCallbackHandler")
    .load()
    .selectExpr("CAST(value AS STRING)")
    )

Key properties include:

  • kafka.security.protocol = SASL_SSL – Enables encrypted communication over SSL with SASL authentication
  • kafka.sasl.mechanism = AWS_MSK_IAM – Tells Kafka to use the IAM based SASL mechanism
  • kafka.sasl.jaas.config = software.amazon.msk.auth.iam.IAMLoginModule required; – Specifies the login module provided by AWS for IAM integration
  • kafka.sasl.client.callback.handler.class = software.amazon.msk.auth.iam.IAMClientCallbackHandler – Handles the actual signing and authentication using the IAM role

With these settings, Spark uses the IAM credentials attached to the EMR Serverless job execution role to authenticate to MSK Serverless without needing additional credentials, certificates, or secrets.

Data processing using an EMR Serverless streaming job with Amazon MSK IAM authentication

Complete the following steps to run a Spark Streaming job to process the data from MSK Serverless:

  1. Submit the Spark Streaming job to EMR Serverless using the AWS Command Line Interface (AWS CLI), which is already installed on the EC2 instance.
  2. Log in to the EC2 instance using Session Manager. Choose the instance msk-emr-serverless-blog and then choose Connect.
  3. Run the following command to submit the streaming job. Provide the parameters from the CloudFormation stack output.
sudo su - ec2-user

aws emr-serverless start-job-run \
--application-id <APPLICATION ID> \
--execution-role-arn <EXECUTION ROLE ARN> \
--mode 'STREAMING' \
--job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<EMR BLOG SCRIPT BUCKET>/emr_pyspark_streaming_script/pysparkStreamingBlog.py",
"entryPointArguments":["--topic_input","sales_data_topic","--kafka_bootstrap_servers","<BOOTSTRAP URL WITH PORT>","--output_s3_path","s3://<EMR STREAMING OUTPUT BUCKET>/output/sales-order-data/","--checkpointLocation","s3://<EMR STREAMING OUTPUT BUCKET>/checkpointing/checkpoint-sales-order-data/","--database_name","emrblog","--table_name","sales_order_data"],
"sparkSubmitParameters": "--conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory --conf spark.executor.cores=2 --conf spark.executor.memory=5g --conf spark.driver.cores=2 --conf spark.driver.memory=5g --conf spark.executor.instances=5 --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1,software.amazon.msk:aws-msk-iam-auth:2.2.0"
}}'
  1. After you submit the job, log in to EMR Studio using the URL in the EmrServerlessStudioURL value from the CloudFormation stack output.
  2. In the navigation pane, choose Applications under Serverless.
  3. Choose the application ID in the EmrServerlessSparkApplicationID value from the CloudFormation stack output.
  4. On the Streaming job runs tab, verify that the job has been submitted and wait for it to begin running.

Validate the data in Athena

After the EMR Serverless Spark Streaming job ran and created the table for the processed data in the Data Catalog, follow these steps to validate the data using Athena:

  1. On the Athena console, open the query editor.
  2. Choose the Data Catalog as the data source.
  3. Choose the database emrblog that the streaming job created.
  4. To validate the data, run the following query:
SELECT 
    DATE_TRUNC('minute', date) AS minute_window, 
    ROUND(SUM(total_amount), 2) AS total_amount
FROM 
    emrblog.sales_order_data
WHERE 
    DATE_TRUNC('day', date) = CURRENT_DATE
GROUP BY 
    DATE_TRUNC('minute', date)
ORDER BY 
    minute_window DESC;

Clean up

To clean up your resources, complete the following steps:

  1. Log in to EMR Studio using the URL from the EmrServerlessStudioURL value in the CloudFormation stack output.
  2. In the navigation pane, choose Applications under Serverless.
  3. Choose the application ID from the EmrServerlessSparkApplicationID value in the CloudFormation stack output.
  4. On the Streaming job runs tab, select the job that has been running and cancel the job run.
  5. On the AWS CloudFormation console, delete the CloudFormation stack vpc-msk-emr-serverless-studio.

Conclusion

In this post, we showcased a serverless pipeline for streaming data with IAM authentication, empowering you to focus on deriving insights from your analytics. You can customize the EMR Serverless Spark Streaming code to apply transformations and filters, so only valid data is loaded into Amazon S3. This solution combines the power of Amazon EMR Spark Serverless streaming with MSK Serverless, securely integrated through IAM authentication. Now you can streamline your streaming processes without the complexity of managing Amazon MSK and Amazon EMR Spark Streaming integrations.


About the Authors

Shubham Purwar is an AWS Analytics Specialist Solution Architect. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on the AWS platform. With deep expertise in AWS analytics services, he collaborates with customers to uncover their distinct business requirements and create customized solutions that deliver actionable insights and drive business growth. In his free time, Shubham loves to spend time with his family and travel around the world.

Nitin Kumar is a Cloud Engineer (ETL) at AWS, specialized in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. He is committed to helping customers overcome ETL challenges and develop scalable data processing and analytics pipelines on AWS. In his free time, he likes to watch movies and spend time with his family.

Prashanthi Chinthala is a Cloud Engineer (DIST) at AWS. She helps customers overcome EMR challenges and develop scalable data processing and analytics pipelines on AWS.

Accelerate lightweight analytics using PyIceberg with AWS Lambda and an AWS Glue Iceberg REST endpoint

Post Syndicated from Sotaro Hikita original https://aws.amazon.com/blogs/big-data/accelerate-lightweight-analytics-using-pyiceberg-with-aws-lambda-and-an-aws-glue-iceberg-rest-endpoint/

For modern organizations built on data insights, effective data management is crucial for powering advanced analytics and machine learning (ML) activities. As data use cases become more complex, data engineering teams require sophisticated tooling to handle versioning, increasing data volumes, and schema changes across multiple data sources and applications.

Apache Iceberg has emerged as a popular choice for data lakes, offering ACID (Atomicity, Consistency, Isolation, Durability) transactions, schema evolution, and time travel capabilities. Iceberg tables can be accessed from various distributed data processing frameworks like Apache Spark and Trino, making it a flexible solution for diverse data processing needs. Among the available tools for working with Iceberg, PyIceberg stands out as a Python implementation that enables table access and management without requiring distributed compute resources.

In this post, we demonstrate how PyIceberg, integrated with the AWS Glue Data Catalog and AWS Lambda, provides a lightweight approach to harness Iceberg’s powerful features through intuitive Python interfaces. We show how this integration enables teams to start working with Iceberg tables with minimal setup and infrastructure dependencies.

PyIceberg’s key capabilities and advantages

One of PyIceberg’s primary advantages is its lightweight nature. Without requiring distributed computing frameworks, teams can perform table operations directly from Python applications, making it suitable for small to medium-scale data exploration and analysis with minimal learning curve. In addition, PyIceberg is integrated with Python data analysis libraries like Pandas and Polars, so data users can use their existing skills and workflows.

When using PyIceberg with the Data Catalog and Amazon Simple Storage Service (Amazon S3), data teams can store and manage their tables in a completely serverless environment. This means data teams can focus on analysis and insights rather than infrastructure management.

Furthermore, Iceberg tables managed through PyIceberg are compatible with AWS data analytics services. Although PyIceberg operates on a single node and has performance limitations with large data volumes, the same tables can be efficiently processed at scale using services such as Amazon Athena and AWS Glue. This enables teams to use PyIceberg for rapid development and testing, then transition to production workloads with larger-scale processing engines—while maintaining consistency in their data management approach.

Representative use case

The following are common scenarios where PyIceberg can be particularly useful:

  • Data science experimentation and feature engineering – In data science, experiment reproducibility is crucial for maintaining reliable and efficient analyses and models. However, continuously updating organizational data makes it challenging to manage data snapshots for important business events, model training, and consistent reference. Data scientists can query historical snapshots through time travel capabilities and record important versions using tagging features. With PyIceberg, they can receive these benefits in their Python environment using familiar tools like Pandas. Thanks to Iceberg’s ACID capabilities, they can access consistent data even when tables are being actively updated.
  • Serverless data processing with Lambda – Organizations often need to process data and maintain analytical tables efficiently without managing complex infrastructure. Using PyIceberg with Lambda, teams can build event-driven data processing and scheduled table updates through serverless functions. PyIceberg’s lightweight nature makes it well-suited for serverless environments, enabling simple data processing tasks like data validation, transformation, and ingestion. These tables remain accessible for both updates and analytics through various AWS services, allowing teams to build efficient data pipelines without managing servers or clusters.

Event-driven data ingestion and analysis with PyIceberg

In this section, we explore a practical example of using PyIceberg for data processing and analysis using NYC yellow taxi trip data. To simulate an event-driven data processing scenario, we use Lambda to insert sample data into an Iceberg table, representing how real-time taxi trip records might be processed. This example will demonstrate how PyIceberg can streamline workflows by combining efficient data ingestion with flexible analysis capabilities.

Imagine your team faces several requirements:

  • The data processing solution needs to be cost-effective and maintainable, avoiding the complexity of managing distributed computing clusters for this moderately-sized dataset.
  • Analysts need the ability to perform flexible queries and explorations using familiar Python tools. For example, they might need to compare historical snapshots with current data to analyze trends over time.
  • The solution should have the ability to expand to be more scalable in the future.

To address these requirements, we implement a solution that combines Lambda for data processing with Jupyter notebooks for analysis, both powered by PyIceberg. This approach provides a lightweight yet robust architecture that maintains data consistency while enabling flexible analysis workflows. At the end of the walkthrough, we also query this data using Athena to demonstrate compatibility with multiple Iceberg-supporting tools and show how the architecture can scale.

We walk through the following high-level steps:

  1. Use Lambda to write sample NYC yellow taxi trip data to an Iceberg table on Amazon S3 using PyIceberg with an AWS Glue Iceberg REST endpoint. In a real-world scenario, this Lambda function would be triggered by an event from a queuing component like Amazon Simple Queue Service (Amazon SQS). For more details, see Using Lambda with Amazon SQS.
  2. Analyze table data in a Jupyter notebook using PyIceberg through the AWS Glue Iceberg REST endpoint.
  3. Query the data using Athena to demonstrate Iceberg’s flexibility.

The following diagram illustrates the architecture.

Overall Architecture

When implementing this architecture, it’s important to note that Lambda functions can have multiple concurrent invocations when triggered by events. This concurrent invocation might lead to transaction conflicts when writing to Iceberg tables. To handle this, you should implement an appropriate retry mechanism and carefully manage concurrency levels. If you’re using Amazon SQS as an event source, you can control concurrent invocations through the SQS event source’s maximum concurrency setting.

Prerequisites

The following prerequisites are necessary for this use case:

Set up resources with AWS CloudFormation

You can use the provided CloudFormation template to set up the following resources:

Complete the following steps to deploy the resources:

  1. Choose Launch stack.

  1. For Parameters, pyiceberg_lambda_blog_database is set by default. You can also change the default value. If you change the database name, remember to replace pyiceberg_lambda_blog_database with your chosen name in all subsequent steps. Then, choose Next.
  2. Choose Next.
  3. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  4. Choose Submit.

Build and run a Lambda function

Let’s build a Lambda function to process incoming records using PyIceberg. This function creates an Iceberg table called nyc_yellow_table in the database pyiceberg_lambda_blog_database in the Data Catalog if it doesn’t exist. It then generates sample NYC taxi trip data to simulate incoming records and inserts it into nyc_yellow_table.

Although we invoke this function manually in this example, in real-world scenarios, this Lambda function would be triggered by actual events, such as messages from Amazon SQS. When implementing real-world use cases, the function code must be modified to receive the event data and process it based on the requirements.

We deploy the function using container images as the deployment package. To create a Lambda function from a container image, build your image on CloudShell and push it to an ECR repository. Complete the following steps:

  1. Sign in to the AWS Management Console and launch CloudShell.
  2. Create a working directory.
mkdir pyiceberg_blog
cd pyiceberg_blog
  1. Download the Lambda script lambda_function.py.
aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-5013/lambda_function.py .

This script performs the following tasks:

  • Creates an Iceberg table with the NYC taxi schema in the Data Catalog
  • Generates a random NYC taxi dataset
  • Inserts this data into the table

Let’s break down the essential parts of this Lambda function:

  • Iceberg catalog configuration – The following code defines an Iceberg catalog that connects to the AWS Glue Iceberg REST endpoint:
# Configure the catalog
catalog_properties = {
   "type": "rest",
   "uri": f"https://glue.{region}.amazonaws.com/iceberg",
   "s3.region": region,
   "rest.sigv4-enabled": "true",
   "rest.signing-name": "glue",
   "rest.signing-region": region
}
catalog = load_catalog(**catalog_properties)
  • Table schema definition – The following code defines the Iceberg table schema for the NYC taxi dataset. The table includes:
    • Schema columns defined in the Schema
    • Partitioning by vendorid and tpep_pickup_datetime using PartitionSpec
    • Day transform applied to tpep_pickup_datetime for daily record management
    • Sort ordering by tpep_pickup_datetime and tpep_dropoff_datetime

When applying the day transform to timestamp columns, Iceberg automatically handles date-based partitioning hierarchically. This means a single day transform enables partition pruning at the year, month, and day levels without requiring explicit transforms for each level. For more details about Iceberg partitioning, see Partitioning.

# Table Definition
schema = Schema(
    NestedField(field_id=1, name="vendorid", field_type=LongType(), required=False),
    NestedField(field_id=2, name="tpep_pickup_datetime", field_type=TimestampType(), required=False),
    NestedField(field_id=3, name="tpep_dropoff_datetime", field_type=TimestampType(), required=False),
    NestedField(field_id=4, name="passenger_count", field_type=LongType(), required=False),
    NestedField(field_id=5, name="trip_distance", field_type=DoubleType(), required=False),
    NestedField(field_id=6, name="ratecodeid", field_type=LongType(), required=False),
    NestedField(field_id=7, name="store_and_fwd_flag", field_type=StringType(), required=False),
    NestedField(field_id=8, name="pulocationid", field_type=LongType(), required=False),
    NestedField(field_id=9, name="dolocationid", field_type=LongType(), required=False),
    NestedField(field_id=10, name="payment_type", field_type=LongType(), required=False),
    NestedField(field_id=11, name="fare_amount", field_type=DoubleType(), required=False),
    NestedField(field_id=12, name="extra", field_type=DoubleType(), required=False),
    NestedField(field_id=13, name="mta_tax", field_type=DoubleType(), required=False),
    NestedField(field_id=14, name="tip_amount", field_type=DoubleType(), required=False),
    NestedField(field_id=15, name="tolls_amount", field_type=DoubleType(), required=False),
    NestedField(field_id=16, name="improvement_surcharge", field_type=DoubleType(), required=False),
    NestedField(field_id=17, name="total_amount", field_type=DoubleType(), required=False),
    NestedField(field_id=18, name="congestion_surcharge", field_type=DoubleType(), required=False),
    NestedField(field_id=19, name="airport_fee", field_type=DoubleType(), required=False),
)

# Define partition spec
partition_spec = PartitionSpec(
    PartitionField(source_id=1, field_id=1001, transform=IdentityTransform(), name="vendorid_idenitty"),
    PartitionField(source_id=2, field_id=1002, transform=DayTransform(), name="tpep_pickup_day"),
)

# Define sort order
sort_order = SortOrder(
    SortField(source_id=2, transform=DayTransform()),
    SortField(source_id=3, transform=DayTransform())
)

database_name = os.environ.get('GLUE_DATABASE_NAME')
table_name = os.environ.get('ICEBERG_TABLE_NAME')
identifier = f"{database_name}.{table_name}"

# Create the table if it doesn't exist
location = f"s3://pyiceberg-lambda-blog-{account_id}-{region}/{database_name}/{table_name}"
if not catalog.table_exists(identifier):
    table = catalog.create_table(
        identifier=identifier,
        schema=schema,
        location=location,
        partition_spec=partition_spec,
        sort_order=sort_order
    )
else:
    table = catalog.load_table(identifier=identifier)
  • Data generation and insertion – The following code generates random data and inserts it into the table. This example demonstrates an append-only pattern, where new records are continuously added to track business events and transactions:
# Generate random data
records = generate_random_data()
# Convert to Arrow Table
df = pa.Table.from_pylist(records)
# Write data using PyIceberg
table.append(df)
  1. Download the Dockerfile. It defines the container image for your function code.
aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-5013/Dockerfile .
  1. Download the requirements.txt. It defines the Python packages required for your function code.
aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-5013/requirements.txt .

At this point, your working directory should contain the following three files:

  • Dockerfile
  • lambda_function.py
  • requirements.txt
  1. Set the environment variables. Replace <account_id> with your AWS account ID:
export AWS_ACCOUNT_ID=<account_id>
  1. Build the Docker image:
docker build --provenance=false -t localhost/pyiceberg-lambda .

# Confirm built image
docker images | grep pyiceberg-lambda
  1. Set a tag to the image:
docker tag localhost/pyiceberg-lambda:latest ${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com/pyiceberg-lambda-repository:latest
  1. Log in to the ECR repository created by AWS CloudFormation:
aws ecr get-login-password --region ${AWS_REGION} | docker login --username AWS --password-stdin ${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com
  1. Push the image to the ECR repository:
docker push ${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com/pyiceberg-lambda-repository:latest
  1. Create a Lambda function using the container image you pushed to Amazon ECR:
aws lambda create-function \
--function-name pyiceberg-lambda-function \
--package-type Image \
--code ImageUri=${AWS_ACCOUNT_ID}.dkr.ecr.${AWS_REGION}.amazonaws.com/pyiceberg-lambda-repository:latest \
--role arn:aws:iam::${AWS_ACCOUNT_ID}:role/pyiceberg-lambda-function-role-${AWS_REGION} \
--environment "Variables={ICEBERG_TABLE_NAME=nyc_yellow_table, GLUE_DATABASE_NAME=pyiceberg_lambda_blog_database}" \
--region ${AWS_REGION} \
--timeout 60 \
--memory-size 1024
  1. Invoke the function at least five times to create multiple snapshots, which we will examine in the following sections. Note that we are invoking the function manually to simulate event-driven data ingestion. In real world scenarios, Lambda functions will be automatically invoked with event-driven fashion.
aws lambda invoke \
--function-name arn:aws:lambda:${AWS_REGION}:${AWS_ACCOUNT_ID}:function:pyiceberg-lambda-function \
--log-type Tail \
outputfile.txt \
--query 'LogResult' | tr -d '"' | base64 -d

At this point, you have deployed and run the Lambda function. The function creates the nyc_yellow_table Iceberg table in the pyiceberg_lambda_blog_database database. It also generates and inserts sample data into this table. We will explore the records in the table in later steps.

For more detailed information about building Lambda functions with containers, see Create a Lambda function using a container image.

Explore the data with Jupyter using PyIceberg

In this section, we demonstrate how to access and analyze the data stored in Iceberg tables registered in the Data Catalog. Using a Jupyter notebook with PyIceberg, we access the taxi trip data created by our Lambda function and examine different snapshots as new records arrive. We also tag specific snapshots to retain important ones, and create new tables for further analysis.

Complete the following steps to open the notebook with Jupyter on the SageMaker AI notebook instance:

  1. On the SageMaker AI console, choose Notebooks in the navigation pane.
  2. Choose Open JupyterLab next to the notebook that you created using the CloudFormation template.

notebook list

  1. Download the notebook and open it in a Jupyter environment on your SageMaker AI notebook.

upload notebook

  1. Open uploaded pyiceberg_notebook.ipynb.
  2. In the kernel selection dialog, leave the default option and choose Select.

select kernel

From this point forward, you will work through the notebook by running cells in order.

Connecting Catalog and Scanning Tables

You can access the Iceberg table using PyIceberg. The following code connects to the AWS Glue Iceberg REST endpoint and loads the nyc_yellow_table table on the pyiceberg_lambda_blog_database database:

import pyarrow as pa
from pyiceberg.catalog import load_catalog
import boto3

# Set AWS region
sts = boto3.client('sts')
region = sts._client_config.region_name

# Configure catalog connection properties
catalog_properties = {
    "type": "rest",
    "uri": f"https://glue.{region}.amazonaws.com/iceberg",
    "s3.region": region,
    "rest.sigv4-enabled": "true",
    "rest.signing-name": "glue",
    "rest.signing-region": region
}

# Specify database and table names
database_name = "pyiceberg_lambda_blog_database"
table_name = "nyc_yellow_table"

# Load catalog and get table
catalog = load_catalog(**catalog_properties)
table = catalog.load_table(f"{database_name}.{table_name}")

You can query full data from the Iceberg table as an Apache Arrow table and convert it to a Pandas DataFrame.

scan table

Working with Snapshots

One of the important features of Iceberg is snapshot-based version control. Snapshots are automatically created whenever data changes occur in the table. You can retrieve data from a specific snapshot, as shown in the following example.

working with snapshots

# Get data from a specific snapshot ID
snapshot_id = snapshots.to_pandas()["snapshot_id"][3]
snapshot_pa_table = table.scan(snapshot_id=snapshot_id).to_arrow()
snapshot_df = snapshot_pa_table.to_pandas()

You can compare the current data with historical data from any point in time based on snapshots. In this case, you are comparing the differences in data distribution between the latest table and a snapshot table:

# Compare the distribution of total_amount in the specified snapshot and the latest data.
import matplotlib.pyplot as plt

plt.figure(figsize=(4, 3))
df['total_amount'].hist(bins=30, density=True, label="latest", alpha=0.5)
snapshot_df['total_amount'].hist(bins=30, density=True, label="snapshot", alpha=0.5)
plt.title('Distribution of total_amount')
plt.xlabel('total_amount')
plt.ylabel('relative Frequency')
plt.legend()
plt.show()

matplotlib graph

Tagging snapshots

You can tag specific snapshots with an arbitrary name and query specific snapshots with that name later. This is useful when managing snapshots of important events.

In this example, you query a snapshot specifying the tag checkpointTag. Here, you are using the polars to create a new DataFrame by adding a new column called trip_duration based on existing columns tpep_dropoff_datetime and tpep_pickup_datetime columns:

# retrive tagged snapshot table as polars data frame
import polars as pl

# Get snapshot id from tag name
df = table.inspect.refs().to_pandas()
filtered_df = df[df["name"] == tag_name]
tag_snapshot_id = filtered_df["snapshot_id"].iloc[0]

# Scan Table based on the snapshot id
tag_pa_table = table.scan(snapshot_id=tag_snapshot_id).to_arrow()
tag_df = pl.from_arrow(tag_pa_table)

# Process the data adding a new column "trip_duration" from check point snapshot.
def preprocess_data(df):
    df = df.select(["vendorid", "tpep_pickup_datetime", "tpep_dropoff_datetime", 
                    "passenger_count", "trip_distance", "fare_amount"])
    df = df.with_columns(
        ((pl.col("tpep_dropoff_datetime") - pl.col("tpep_pickup_datetime"))
         .dt.total_seconds() // 60).alias("trip_duration"))
    return df

processed_df = preprocess_data(tag_df)
display(processed_df)
print(processed_df["trip_duration"].describe())

processed-df

Create a new table from the processed DataFrame with the trip_duration column. This step illustrates how to prepare data for potential future analysis. You can explicitly specify the snapshot of the data that the processed data is referring to by using a tag, even if the underlying table has been changed.

# write processed data to new iceberg table
account_id = sts.get_caller_identity()["Account"] 

new_table_name = "processed_" + table_name
location = f"s3://pyiceberg-lambda-blog-{account_id}-{region}/{database_name}/{new_table_name}"

pa_new_table = processed_df.to_arrow()
schema = pa_new_table.schema
identifier = f"{database_name}.{new_table_name}"

new_table = catalog.create_table(
                identifier=identifier,
                schema=schema,
                location=location
            )
            
# show new table's schema
print(new_table.schema())
# insert processed data to new table
new_table.append(pa_new_table)

Let’s query this new table made from processed data with Athena to demonstrate the Iceberg table’s interoperability.

Query the data from Athena

  1. In the Athena query editor, you can query the table pyiceberg_lambda_blog_database.processed_nyc_yellow_table created from the notebook in the previous section:
SELECT * FROM "pyiceberg_lambda_blog_database"."processed_nyc_yellow_table" limit 10;

query with athena

By completing these steps, you’ve built a serverless data processing solution using PyIceberg with Lambda and an AWS Glue Iceberg REST endpoint. You’ve worked with PyIceberg to manage and analyze data using Python, including snapshot management and table operations. In addition, you ran the query using another engine, Athena, which shows the compatibility of the Iceberg table.

Clean up

To clean up the resources used in this post, complete the following steps:

  1. On the Amazon ECR console, navigate to the repository pyiceberg-lambda-repository and delete all images contained in the repository.
  2. On the CloudShell, delete working directory pyiceberg_blog.
  3. On the Amazon S3 console, navigate to the S3 bucket pyiceberg-lambda-blog-<ACCOUNT_ID>-<REGION>, which you created using the CloudFormation template, and empty the bucket.
  4. After you confirm the repository and the bucket are empty, delete the CloudFormation stack pyiceberg-lambda-blog-stack.
  5. Delete the Lambda function pyiceberg-lambda-function that you created using the Docker image.

Conclusion

In this post, we demonstrated how using PyIceberg with the AWS Glue Data Catalog enables efficient, lightweight data workflows while maintaining robust data management capabilities. We showcased how teams can use Iceberg’s powerful features with minimal setup and infrastructure dependencies. This approach allows organizations to start working with Iceberg tables quickly, without the complexity of setting up and managing distributed computing resources.

This is particularly valuable for organizations looking to adopt Iceberg’s capabilities with a low barrier to entry. The lightweight nature of PyIceberg allows teams to begin working with Iceberg tables immediately, using familiar tools and requiring minimal additional learning. As data needs grow, the same Iceberg tables can be seamlessly accessed by AWS analytics services like Athena and AWS Glue, providing a clear path for future scalability.

To learn more about PyIceberg and AWS analytics services, we encourage you to explore the PyIceberg documentation and What is Apache Iceberg?


About the authors

Sotaro Hikita is a Specialist Solutions Architect focused on analytics with AWS, working with big data technologies and open source software. Outside of work, he always seeks out good food and has recently become passionate about pizza.

Shuhei Fukami is a Specialist Solutions Architect focused on Analytics with AWS. He likes cooking in his spare time and has become obsessed with making pizza these days.

Build end-to-end Apache Spark pipelines with Amazon MWAA, Batch Processing Gateway, and Amazon EMR on EKS clusters

Post Syndicated from Avinash Desireddy original https://aws.amazon.com/blogs/big-data/build-end-to-end-apache-spark-pipelines-with-amazon-mwaa-batch-processing-gateway-and-amazon-emr-on-eks-clusters/

Apache Spark workloads running on Amazon EMR on EKS form the foundation of many modern data platforms. EMR on EKS offers benefits by providing managed Spark that integrates seamlessly with other AWS services and your organization’s existing Kubernetes-based deployment patterns.

Data platforms processing large-scale data volumes often require multiple EMR on EKS clusters. In the post Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments, we introduced Batch Processing Gateway (BPG) as a solution for managing Spark workloads across these clusters. Although BPG provides foundational functionality to distribute workloads and support routing for Spark jobs in multi-cluster environments, enterprise data platforms require additional features for a comprehensive data processing pipeline.

This post shows how to enhance the multi-cluster solution by integrating Amazon Managed Workflows for Apache Airflow (Amazon MWAA) with BPG. By using Amazon MWAA, we add job scheduling and orchestration capabilities, enabling you to build a comprehensive end-to-end Spark-based data processing pipeline.

Overview of solution

Consider HealthTech Analytics, a healthcare analytics company managing two distinct data processing workloads. Their Clinical Insights Data Science team processes sensitive patient outcome data requiring HIPAA compliance and dedicated resources, and their Digital Analytics team handles website interaction data with more flexible requirements. As their operation grows, they face increasing challenges in managing these diverse workloads efficiently.

The company needs to maintain strict separation between protected health information (PHI) and non-PHI data processing, while also addressing different cost center requirements. The Clinical Insights Data Science team runs critical end-of-day batch processes that need guaranteed resources, whereas the Digital Analytics team can use cost-optimized spot instances for their variable workloads. Additionally, data scientists from both teams require environments for experimentation and prototyping as needed.

This scenario presents an ideal use case for implementing a data pipeline using Amazon MWAA, BPG, and multiple EMR on EKS clusters. The solution needs to route different Spark workloads to appropriate clusters based on security requirements and cost profiles, while maintaining the necessary isolation and compliance controls. To effectively manage such an environment, we need a solution that maintains clean separation between application and infrastructure management concerns and stitching together multiple components into a robust pipeline.

Our solution consists of integrating Amazon MWAA with BPG through an Airflow custom operator for BPG called BPGOperator. This operator encapsulates the infrastructure management logic needed to interact with BPG. BPGOperator provides a clean interface for job submission through Amazon MWAA. When executed, the operator communicates with BPG, which then routes the Spark workloads to available EMR on EKS clusters based on predefined routing rules.

The following architecture diagram illustrates the components and their interactions.

Image showing the end to end architecture for end-to-end pipeline

The solution works through the following steps:

  • Amazon MWAA executes scheduled DAGs using BPGOperator. Data engineers create DAGs using this operator, requiring only the Spark application configuration file and basic scheduling parameters.
  • BPGOperator authenticates and submits jobs to the BPG submit endpoint POST:/apiv2/spark. It handles all HTTP communication details, manages authentication tokens, and provides secure transmission of job configurations.
  • BPG routes submitted jobs to EMR on EKS clusters based on predefined routing rules. These routing rules are managed centrally through BPG configuration, allowing rules-based distribution of workloads across multiple clusters.
  • BPGOperator monitors job status, captures logs, and handles execution retries. It polls the BPG job status endpoint GET:/apiv2/spark/{subID}/status and streams logs to Airflow by polling the GET:/apiv2/log endpoint every second. The BPG log endpoint retrieves the most current log information directly from the Spark Driver Pod.
  • The DAG execution progresses to subsequent tasks based on job completion status and defined dependencies. BPGOperator communicates the job status through Airflow’s built-in task communication system, enabling complex workflow orchestration.

Refer to the BPG REST API interface documentation for additional details.

This architecture provides several key benefits:

  • Separation of responsibilities – Data Engineering and Platform Engineering teams in enterprise organizations typically maintain distinct responsibilities. The modular design in this solution enables platform engineers to configure BPGOperator and manage EMR on EKS clusters, while data engineers maintain DAGs.
  • Centralized code managementBPGOperator encapsulates all core functionalities required for Amazon MWAA DAGs to submit Spark jobs through BPG into a single, reusable Python module. This centralization minimizes code duplication across DAGs and improves maintainability by providing a standardized interface for job submissions.

Airflow custom operator for BPG

An Airflow Operator is a template for a predefined Task that you can define declaratively inside your DAGs. Airflow provides multiple built-in operators such as BashOperator, which executes bash commands, PythonOperator, which executes Python functions, and EmrContainerOperator, which submits new jobs to an EMR on EKS cluster. However, no built-in operators exist to implement all the steps required for the Amazon MWAA integration with BPG.

Airflow allows you to create new operators to suit your specific requirements. This operator type is known as a custom operator. A custom operator encapsulates the custom infrastructure-related logic in a single, maintainable component. Custom operators are created by extending the airflow.models.baseoperator.BaseOperator class. We have developed and open sourced an Airflow custom operator for BPG called BPGOperator, which implements the necessary steps to provide a seamless integration of Amazon MWAA with BPG.

The following class diagram provides a detailed view of the BPGOperator implementation.

Image showing class diagram for BPGOperator implementation

When a DAG includes a BPGOperator task, the Amazon MWAA instance triggers the operator to send a job request to BPG. The operator typically performs the following steps:

  • Initialize job BPGOperator prepares the job payload, including input parameters, configurations, connection details, and other metadata required by BPG.
  • Submit job BPGOperator handles HTTP POST requests to submit jobs to BPG endpoints with the provided configurations.
  • Monitor job execution BPGOperator checks the job status, polling BPG until the job completes successfully or fails. The monitoring process includes handling various job states, managing timeout scenarios, and responding to errors that occur during job execution.
  • Handle job completion – Upon completion, BPGOperator captures the job results, logs relevant details, and can trigger downstream tasks based on the execution outcome.

The following sequence diagram illustrates the interaction flow between the Airflow DAG, BPGOperator, and BPG.

Image showing sequence diagram for the interaction between the Airflow DAG, BPGOperator, and BPG.

Deploying the solution

In the remainder of this post, you will implement the end-to-end pipeline to run Spark jobs on multiple EMR on EKS clusters. You will begin by deploying the common components that serve as the foundation for building the pipelines. Next, you will deploy and configure BPG on an EKS cluster, followed by deploying and configuring BPGOperator on Amazon MWAA. Finally, you will execute Spark jobs on multiple EMR on EKS clusters from Amazon MWAA.

To streamline the setup process, we’ve automated the deployment of all infrastructure components required for this post, so you can focus on the essential aspects of job submission to build an end-to-end pipeline. We provide detailed information to help you understand each step, simplifying the setup while preserving the learning experience.

To showcase the solution, you will create three clusters and an Amazon MWAA environment:

  • Two EMR on EKS clusters: analytics-cluster and datascience-cluster
  • An EKS cluster: gateway-cluster
  • An Amazon MWAA environment: airflow-environment

analytics-cluster and datascience-cluster serve as data processing clusters that run Spark workloads, gateway-cluster hosts BPG, and airflow-environment hosts Airflow for job orchestration and scheduling.

You can find the code base in the GitHub repo.

Prerequisites

Before you deploy this solution, make sure that the following prerequisites are in place:

Set up common infrastructure

This step handles the setup of networking infrastructure, including virtual private cloud (VPC) and subnets, along with the configuration of AWS Identity and Access Management (IAM) roles, Amazon Simple Storage Service (Amazon S3) storage, Amazon Elastic Container Registry (Amazon ECR) repository for BPG images, Amazon Aurora PostgreSQL-Compatible Edition database, Amazon MWAA environment, and both EKS and EMR on EKS clusters with a preconfigured Spark operator. With this infrastructure automatically provisioned, you can concentrate on the subsequent steps without getting caught up in basic setup tasks.

  1. Clone the repository to your local machine and set the two environment variables. Replace <AWS_REGION> with the AWS Region where you want to deploy these resources.
    git clone https://github.com/aws-samples/sample-mwaa-bpg-emr-on-eks-spark-pipeline.git
    cd sample-mwaa-bpg-emr-on-eks-spark-pipeline
    			
    export REPO_DIR=$(pwd)
    export AWS_REGION=<AWS_REGION>

  2. Execute the following script to create the common infrastructure:
    cd ${REPO_DIR}/infra
    ./setup.sh

  3. To verify successful infrastructure deployment, navigate to the AWS CloudFormation console, open your stack, and check the Events, Resources, and Outputs tabs for completion status, details, and list of resources created.

You have completed the setup of the common components that serve as the foundation for rest of the implementation.

Set up Batch Processing Gateway

This section builds the Docker image for BPG, deploys the helm chart on the gateway-cluster EKS cluster, and exposes the BPG endpoint using Kubernetes service of type LoadBalancer. Complete the following steps:

  1. Deploy BPG on the gateway-cluster EKS cluster:
    cd ${REPO_DIR}/infra/bpg
    ./configure_bpg.sh

  2. Verify the deployment by listing the pods and viewing the pod logs:
    kubectl get pods --namespace bpg
    kubectl logs <BPG-PODNAME> --namespace bpg

    Review the logs and confirm there are no errors or exceptions.

  3. Exec into the BPG pod and verify the health check:
    kubectl exec -it <BPG-PODNAME> -n bpg -- bash
    curl -u admin:admin localhost:8080/skatev2/healthcheck/status

    The healthcheck API should return a successful response of {"status":"OK"}, confirming successful deployment of BPG on the gateway-cluster EKS cluster.

We have successfully configured BPG on gateway-cluster and set up EMR on EKS for both datascience-cluster and analytics-cluster. This is where we left off in the previous blog post. In the next steps, we will configure Amazon MWAA with BPGOperator, and then write and submit DAGs to demonstrate an end-to-end Spark-based data pipeline.

Configure the Airflow operator for BPG on Amazon MWAA

This section configures the BPGOperator plugin on the Amazon MWAA environment airflow-environment. Complete the following steps:

  1. Configure BPGOperator on Amazon MWAA:
    cd ${REPO_DIR}/bpg_operator
    ./configure_bpg_operator.sh

  2. On the Amazon MWAA console, navigate to the airflow-environment environment.
  3. Choose Open Airflow UI, and in the Airflow UI, choose the Admin dropdown menu and choose Plugins.
    You will see the BPGOperator plugin listed in the Airflow UI.
    Image showing BPGOperator plugin listed in the Airflow UI

Configure Airflow connections for BPG integration

This section guides you through setting up the Airflow connections that enable secure communication between your Amazon MWAA environment and BPG. BPGOperator uses the configured connection to authenticate and interact with BPG endpoints.

Execute the following script to configure the Airflow connection bpg_connection.

cd $REPO_DIR/airflow
./configure_connections.sh

In the Airflow UI, choose the Admin dropdown menu and choose Connections. You will see the bpg_connection listed in the Airflow UI.

Image showing Airflow Connections page with bpg_connection configured.

Configure the Airflow DAG to execute Spark jobs

This step configures an Airflow DAG to run a sample application. In this case, we will submit a DAG containing multiple sample Spark jobs using Amazon MWAA to EMR on EKS clusters using BPG. Please wait for few minutes for the DAG to appear in the Airflow UI.

cd $REPO_DIR/jobs
./configure_job.sh

Trigger the Amazon MWAA DAG

In this step, we trigger the Airflow DAG and observe the job execution behavior, including reviewing the Spark logs in the Airflow UI:

  1. In the Airflow UI, review the MWAASparkPipelineDemoJob DAG and choose the play icon trigger the DAG.
    Image showing sample Airflow Job, highlighting the play button to trigger the job
  2. Wait for DAG to complete successfully.
    Upon successful completion of the DAG, you should see Success:1 under the Runs column.
  3. In the Airflow UI, locate and choose the MWAASparkPipelineDemoJob DAG.
  4. On the Graph tab, choose any task (in this example, we select the calculate_pi task) and then choose the Logs
    Image showing the MWAASparkPipelineDemoJob's graph view
  5. View the Spark logs in the Airflow UI.
    Image showing the MWAASparkPipelineDemoJob calculate_pi task logs

Migrate existing Airflow DAGs to use BPG

In enterprise data platforms, a typical data pipeline consists of Amazon MWAA submitting Spark jobs to multiple EMR on EKS clusters using the SparkKubernetesOperator and an Airflow Connection of type Kubernetes. An Airflow Connection is a set of parameters and credentials used to establish communication between Amazon MWAA and external systems or services. A DAG refers to the connection name and connects to the external system.

The following diagram shows the typical architecture.
Image showing the existing job execution workflows not using BPG

In this setup, Airflow DAGs typically uses SparkKubernetesOperator and SparkKubernetesSensor to submit Spark jobs to a remote EMR on EKS cluster using kubernetes_conn_id=<connection_name>.

The following code snippet shows the relevant details:

# Submit Spark-Pi job using Kubernetes connection
submit_spark_pi = SparkKubernetesOperator(
	task_id='submit_spark_pi',
	namespace='default',
	application_file=spark_pi_yaml,
	kubernetes_conn_id='emr_on_eks_connection_[1|2]',  # Connection ID defined in Airflow
	dag=dag
)

To migrate the infrastructure to a BPG-based infrastructure without impacting the continuity of the environment, we can deploy a parallel infrastructure using BPG, create a new Airflow Connection for BPG, and incrementally migrate the DAGs to use the new connection. By doing so, we won’t disrupt the existing infrastructure until the BPG-based infrastructure is completely operational, including the migration of all existing DAGs.

The following diagram showcases the interim state where both the Kubernetes connection and BPG connection are operational. Blue arrows indicate the existing workflow paths, and red arrows represent the new BPG-based migration paths.

Image showing the existing workflow paths and the new bpg based migration path

The modified code snippet for the DAG is as follows:

# Submit Spark-Pi job using BPG connection
submit_spark_pi = BPGOperator(
	task_id='submit_spark_pi',
	application_file=spark_pi_yaml,
	application_file_type='yaml'
	connection_id='bpg_connection',  # Connection ID defined in Airflow
	dag=dag
)

Finally, when all the DAGs have been modified to use BPGOperator instead of SparkKubernetesOperator, you can decommission any remnants of the old workflow. The final state of the infrastructure will look like the following diagram.

Image showing the final state of the infrastructure after all the job migrations are complete.

Using this approach, we can seamlessly introduce BPG into an environment that currently uses only Amazon MWAA and EMR on EKS clusters.

Clean up

To avoid incurring future charges from the resources created in this tutorial, clean up your environment after you’ve completed the steps. You can do this by running the cleanup.sh script, which will safely remove all the resources provisioned during the setup:

cd ${REPO_DIR}/setup
./cleanup.sh

Conclusion

In the post Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments, we introduced Batch Processing Gateway as a solution for routing Spark workloads across multiple EMR on EKS clusters. In this post, we demonstrated how to enhance this foundation by integrating BPG with Amazon MWAA. Through our custom BPGOperator, we’ve shown how to build robust end-to-end Spark-based data processing pipelines while maintaining clear separation of responsibilities and centralized code management. Finally, we demonstrated how to seamlessly incorporate the solution into your existing Amazon MWAA and EMR on EKS data platform without impacting operational continuity.

We encourage you to experiment with this architecture in your own environment, adapting it to fit your unique workloads and operational requirements. By implementing this solution, you can build efficient and scalable data processing pipelines that use the full potential of EMR on EKS and Amazon MWAA. Explore further by deploying the solution in your AWS account while adhering to your organizational security best practices and share your experiences with the AWS Big Data community.


About the Authors

Suvojit DasguptaSuvojit Dasgupta is a Principal Data Architect at AWS. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Avinash DesireddyAvinash Desireddy is a Cloud Infrastructure Architect at AWS, passionate about building secure applications and data platforms. He has extensive experience in Kubernetes, DevOps, and enterprise architecture, helping customers containerize applications, streamline deployments, and optimize cloud-native environments.

Best practices for least privilege configuration in Amazon MWAA

Post Syndicated from Elizabeth Davis original https://aws.amazon.com/blogs/big-data/best-practices-for-least-privilege-configuration-in-amazon-mwaa/

Amazon Managed Workflows for Apache Airflow (Amazon MWAA) provides a secure and managed environment to run Apache Airflow on AWS. Airflow is often used in highly regulated industries, such as finance and healthcare. These customers might want to further restrict access and traffic to enhance security posture than what the Amazon MWAA default configurations provide. This post covers some recommended practices.

The principle of least privilege is a fundamental tenet that should be followed diligently. When it comes to configuring AWS services, it’s essential to grant only the minimum required permissions to resources, avoiding overly broad or permissive policies.

In this post, we explore how to apply the principle of least privilege to your Amazon MWAA environment by tightening network security using security groups, network access control lists (ACLs), and virtual private cloud (VPC) endpoints. We also discuss the Amazon MWAA execution and deployment roles and their respective permissions.

Understanding the Amazon MWAA environment

When an Amazon MWAA environment is created, resources are created in an AWS managed service VPC and your customer managed VPC. In the customer VPC provided at environment creation, the necessary resources to run the Airflow environment are deployed, including schedulers and workers running on Amazon Elastic Container Service (Amazon ECS) clusters. These clusters are deployed in your VPC and they assume Elastic Network Interfaces (ENIs) with private IP addresses in the customer account. These ENIs span private subnets across two Availability Zones to connect to the Airflow database and web server, which reside in the service-owned account (if in private access mode). The following diagram illustrates this architecture.

MWAA Architecture

VPC security groups act as virtual firewalls that can control network traffic at the ENI level, or instance level. Security groups are stateful, meaning that inbound traffic is automatically permitted outbound and vice versa. The default security group configuration in a VPC starts with is no inbound rules and an outbound rule allowing all traffic. By definition, a security group with no inbound rules denies all ingress traffic that wasn’t allowed out through the 0.0.0.0/0 outbound rule.

Amazon MWAA offers two web server access modes inside the customer VPC: public and private. Public web server mode must have a way for traffic to access the web servers in the customer-owned VPC through the public internet. This requires routing to the public internet using public subnets and a NAT gateway. A NAT gateway can be used to provide internet access for resources in private subnets. With private access mode, the security group for the Amazon MWAA environment doesn’t need to allow traffic to and from the NAT gateway, only granting access to the Airflow UI to users with appropriate permissions from within the VPC. An Application Load Balancer is only provisioned in public mode to route traffic to the public web servers. The customer must provision the rest of the networking components.

If your Amazon MWAA environment needs to communicate with resources outside your VPC (such as external data sources or APIs), you might need to configure appropriate security group rules and routing to allow the necessary traffic. In such cases, you would typically use a NAT gateway or VPN connection to facilitate the communication between your Amazon MWAA environment and the external resources and VPC endpoints for AWS resources.

For tighter security restrictions, an environment with private routing without internet access is possible, and finer-grained security group rules can be applied and VPC endpoint policies can be used. Because this post is focusing on least privilege, we will focus on the minimum security requirements needed for an Amazon MWAA environment.

Security groups: Minimizing permissions

Your Amazon MWAA environment will have a security group associated with your VPC’s environment resources. This security group is also used by the ENIs created by the interface VPC endpoint that is used to communicate with the database and web server. By default, security groups deny all inbound traffic and security group rules need to be explicitly stated, denoting the ports and source that the instance will allow network traffic from. At a minimum, the Amazon MWAA environment must allow for traffic to and from the Amazon Aurora PostgreSQL-Compatible Edition metadata database that is owned and managed by Amazon MWAA. The metadata database is a crucial component of Airflow that acts as a centralized source of truth for task execution, configuration, and monitoring. Both the scheduler and workers require access to this database to perform their respective roles in orchestrating and running tasks. This database listens on TCP port 5432. Additionally, the web server traffic can be restricted to HTTPS through TCP port 443. At a minimum, the Amazon MWAA security group must have the two inbound rules, detailed in the following table.

Type Protocol Port Range Source Type Source
Custom TCP TCP 5432 Custom sg-xxxxx / my-mwaa-vpc-security-group
HTTPS TCP 443 Custom sg-xxxxx / my-mwaa-vpc-security-group

Many customers have other AWS resources residing in VPCs, to which the Amazon MWAA workers need access. These resources can be granted network access in a private routing configuration using security groups as well. If the resource sits in the same security group, add an additional inbound rule with the port needed. For example, if an Amazon Redshift cluster sits in the same security group, add the following rule.

Type Protocol Port Range Source Type Source
Custom TCP TCP 5439 Custom sg-xxxxx / my-mwaa-vpc-security-group

If the Redshift cluster is in a different security group, change the source to the Redshift security group.

Type Protocol Port Range Source Type Source
Custom TCP TCP 5439 Custom sg-xxxxx / redshift-security-group

If the resources are in another VPC, then VPC peering must be enabled before referencing that other VPC’s security group. For resources that don’t reside in a subnet, a VPC endpoint will also provide private routing to and from the Amazon MWAA environment and those resources. For example, a VPC endpoint for Amazon Simple Storage Service (Amazon S3) can provide enhanced security, improved performance, and lower costs.

Network ACLs: Minimizing permissions

Network ACLs can manage (by allow or deny rules) inbound and outbound traffic at the subnet level. An ACL is stateless, which means that inbound and outbound rules must be specified separately and explicitly. It is used to specify the types of network traffic that are allowed in or out from the instances in a VPC network.

Every Amazon VPC has a default ACL that allows all inbound and outbound traffic, with a rule as follows.

Rule number Type Protocol Port Range Source Allow/Deny
100 All IPv4 traffic All All 0.0.0.0/0 Allow
* All IPv4 traffic All All 0.0.0.0/0 Deny

You can edit the default ACL rules or create a custom ACL and attach it to your subnets. A subnet can only have one ACL attached to it at any time, but one ACL can be attached to multiple subnets. To implement least privilege in your Amazon MWAA environment, restrict the inbound ACL to allow traffic from the metadata database and web server and restrict the outbound to allow traffic to only the clients in the private subnet. Note the following examples use example private IPs for the subnets used.

Inbound NACL

Rule number Type Protocol Port Range Source Allow/Deny Comments
100 Custom TCP TCP 5432 10.192.21.0/16 Allow Allow inbound database traffic from private subnet
110 HTTPS TCP 443 10.192.21.0/16 Allow Allow inbound HTTPS traffic from private subnet
* All traffic All All 0.0.0.0/0 Deny Denies all inbound IPv4 traffic not already handled by a preceding rule (not modifiable)

Outbound NACL

Rule number Type Protocol Port Range Source Allow/Deny Comments
100 Custom TCP TCP 1024-65535 10.192.21.0/24 Allow Allows outbound return IPv4 traffic to clients in private subnet
* All traffic All All 0.0.0.0/0 Deny Denies all outbound IPv4 traffic not already handled by a preceding rule (not modifiable)

VPC endpoints: Minimizing permissions

When you create an Amazon MWAA environment, it is deployed within a VPC. This allows you to control the network access and security of your Airflow deployment. However, some customer workloads executing in the Amazon MWAA environment might need to orchestrate tasks using other AWS services, such as Amazon S3 to access files, AWS Glue to start ETL (extract, transform, and load) jobs, or Amazon Redshift for running data warehouse queries, which reside outside of your VPC. To establish a secure and private connection between your Amazon MWAA environment and these external AWS services, you can use VPC endpoints. The purpose of VPC endpoints in Amazon MWAA is to provide a secure and private connection between your Amazon MWAA environment and other AWS services within your VPC. VPC endpoints are virtual devices that are provisioned within your VPC and act as an entry point for the specified AWS service, allowing your Amazon MWAA environment to communicate with the service using a private IP address, without needing to go through the public internet. The following diagram illustrates this architecture.

VPCEndpointsMWAA

VPC endpoints allow you to keep your Amazon MWAA environment’s network traffic within the AWS network, reducing the exposure to the public internet and enhancing the overall security of your Airflow deployment. Although private VPC endpoints are automatically created for the database and web server, to create a least privileged environment without internet access, additional VPC endpoints will be needed for the additional Amazon MWAA required resources. Amazon S3, Amazon Simple Queue Service (Amazon SQS), Amazon CloudWatch, and optionally AWS Key Management Service (AWS KMS) will need VPC endpoints created. For more details, see Creating the required VPC service endpoints in an Amazon VPC with private routing. Outside of the necessary services, many customers run Amazon MWAA workflows that orchestrate additional AWS services, such as Amazon Redshift, Amazon EMR, and AWS Glue. Let’s look at an example VPC endpoint that we want to use to connect to Amazon Redshift, which is commonly called in the Airflow DAGS using the Redshift Operator for workflows that interact with Amazon Redshift as a data warehouse. For more information on creating Amazon VPC interface endpoints, see Access an AWS service using an interface VPC endpoint.

Create a VPC endpoint

Complete the following steps to create a VPC endpoint using Amazon Virtual Private Cloud (Amazon VPC):

  1. On the Amazon VPC console, create a new VPC endpoint for the amazonaws.region.redshift service, where region is the AWS Region where your Amazon MWAA environment and Redshift cluster are located. Make sure that private DNS is enabled.
  2. Create a VPC endpoint policy. This can be used to limit access to the Redshift cluster only to the Amazon MWAA environment, preventing unauthorized access from other resources. The following is an example policy:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::123456789012:role/YourMWAAExecutionRoleName"
        ]
      },
      "Action": [
        "redshift:DescribeClusters",
        "redshift:DescribeClusterParameters",
        "redshift:DescribeClusterSecurityGroups",
        "redshift:DescribeClusterSubnetGroups",
        "redshift:DescribeEventSubscriptions",
        "redshift:DescribeLoggingStatus",
        "redshift:DescribeReservedNodeOfferings",
        "redshift:DescribeReservedNodes",
        "redshift:DescribeTableRestoreStatus",
        "redshift:DescribeTags",
        "redshift:GetClusterCredentials",
        "redshift:ListTagsForResource",
        "redshift:PurchaseReservedNodeOffering",
        "redshift:ResetClusterParameterGroup",
        "redshift:RestoreFromClusterSnapshot",
        "redshift:RevokeClusterSecurityGroupIngress",
        "redshift:RevokeSnapshotAccess",
        "redshift:ViewQueriesInConsole"
      ],
      "Resource": "arn:aws:redshift:us-east-1:123456789012:cluster/my-redshift-cluster"
    }
  ]
}

The policy contains the following parameters:
  • The Version field specifies the policy language version.
  • The Statement section contains a single statement that allows the specified actions on the Redshift cluster.
  • The Effect field is set to Allow, which means the policy grants the specified permissions.
  • The Principal field specifies the AWS Identity and Access Management (IAM) role associated with your Amazon MWAA execution role, which is authorized to access the Redshift cluster.
  • The Action field lists the specific Redshift actions that the Amazon MWAA execution role is allowed to perform, such as describing the cluster, getting cluster credentials, and restoring from a snapshot.
  • The Resource field specifies the Amazon Resource Name (ARN) of the Redshift cluster that the policy applies to.
  1. Associate the VPC endpoint with the correct route table. This route table should be used by the subnets where your Amazon MWAA environment is deployed. If using a VPC interface endpoint, associate the endpoint with the two private subnets and security group used by Amazon MWAA.
  2. Make sure that the security groups associated with the Amazon MWAA environment and the Redshift cluster allow the necessary inbound and outbound traffic between them. This typically includes allowing access on the Redshift port (typically 5439) from the Amazon MWAA environment’s security group.
  3. On the Amazon MWAA console, under Admin, Connections, update the Redshift connection details to use the VPC endpoint address instead of the public Redshift endpoint. This makes sure that the connection between Amazon MWAA and Amazon Redshift is secure and stays within the VPC.

By configuring VPC endpoints for the AWS services your Amazon MWAA environment needs to access, you can provide secure, private, and efficient communication between your Airflow deployment and AWS resources.

Restricting traffic within AWS with a customer managed endpoints for Amazon MWAA resources

As mentioned earlier, Amazon MWAA integrates with various AWS services, such as CloudWatch for logging, Amazon S3 for DAGs and requirements, Amazon SQS as a messaging middleware, and optionally AWS KMS for encryption. You can create VPC endpoints for these services to make sure traffic stays within the AWS network. Access to these endpoints can be restricted by allowing only the Amazon MWAA security group as the ingress source. For details on how to create these endpoints and policies, see Introducing shared VPC support on Amazon MWAA. If the Amazon MWAA environment was updated after April 2, 2024, it will be on AWS Fargate v1.4 and will not use Amazon Elastic Container Registry (Amazon ECR) and therefore you will not need to create a VPC endpoint for it.

Managing permissions to deploy an Amazon MWAA environment

To create and deploy an Amazon MWAA environment, you need to have the appropriate permissions granted to your IAM user or role. The required permissions can be granted through an IAM policy attached to your user or role. When you create an Amazon MWAA environment, you can specify an execution role that will be assumed by the Airflow workers to perform tasks. The execution role should have the necessary permissions to access the required AWS services and resources based on your workflow requirements. It’s important to follow the principle of least privilege when granting permissions to IAM roles and users. You should only grant the minimum permissions required for your Amazon MWAA environment and Airflow workflows to function correctly.

Amazon MWAA trust policy

Amazon MWAA needs to be able to assume the execution role in order to perform actions on your behalf.  To do this, create a trust policy, allowing the Amazon MWAA service the ability to AssumeRole. To avoid the confused deputy problem, we add a condition to the trust policy, and replace the AWS account number and Region as needed. The following is an example policy:

{
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "Allow",
        "Principal": {
            "Service": ["airflow.amazonaws.com","airflow-env.amazonaws.com"]
        },
        "Action": "sts:AssumeRole",
        "Condition":{
            "ArnLike":{
               "aws:SourceArn":"arn:aws:airflow:your-region:123456789012:environment/your-environment-name"
            },
            "StringEquals":{
               "aws:SourceAccount":"123456789012"
            }
         }
      }
   ]
}

VPC endpoint permissions for the deployer role

Although the service-linked role creates the VPC endpoints, the deployer role requires permissions to create VPC endpoints and perform a dry run. You can limit these permissions by allowing the ec2:CreateVpcEndpoint action and specifying resource ARNs for VPC endpoints, VPCs, subnets, and security groups. Additionally, you can use the aws:CalledVia condition key to restrict access to the airflow.amazonaws.com service.

Amazon MWAA execution role: Required permissions

When creating an Amazon MWAA environment, you need to specify an execution role that grants the necessary permissions for Airflow to interact with other AWS services. Instead of using a wildcard policy, you can create a custom policy with the minimum required permissions.

The following is an example of an execution role policy that allows Amazon MWAA to interact with various services using an AWS managed key:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "airflow:PublishMetrics",
            "Resource": "arn:aws:airflow:{your-region}:{your-account-id}:environment/{your-environment-name}"
        },
        { 
            "Effect": "Deny",
            "Action": "s3:ListAllMyBuckets",
            "Resource": [
                "arn:aws:s3:::{your-s3-bucket-name}",
                "arn:aws:s3:::{your-s3-bucket-name}/*"
            ]
        },
        { 
            "Effect": "Allow",
            "Action": [ 
                "s3:GetObject*",
                "s3:GetBucket*",
                "s3:List*"
            ],
            "Resource": [
                "arn:aws:s3:::{your-s3-bucket-name}",
                "arn:aws:s3:::{your-s3-bucket-name}/*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "logs:CreateLogStream",
                "logs:CreateLogGroup",
                "logs:PutLogEvents",
                "logs:GetLogEvents",
                "logs:GetLogRecord",
                "logs:GetLogGroupFields",
                "logs:GetQueryResults"
            ],
            "Resource": [
                "arn:aws:logs:{your-region}:{your-account-id}:log-group:airflow-{your-environment-name}-*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "logs:DescribeLogGroups"
            ],
            "Resource": [
                "*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "s3:GetAccountPublicAccessBlock"
            ],
            "Resource": [
                "*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": "cloudwatch:PutMetricData",
            "Resource": "*"
        },
        {
            "Effect": "Allow",
            "Action": [
                "sqs:ChangeMessageVisibility",
                "sqs:DeleteMessage",
                "sqs:GetQueueAttributes",
                "sqs:GetQueueUrl",
                "sqs:ReceiveMessage",
                "sqs:SendMessage"
            ],
            "Resource": "arn:aws:sqs:{your-region}:*:airflow-celery-*"
        },
        {
            "Effect": "Allow",
            "Action": [
                "kms:Decrypt",
                "kms:DescribeKey",
                "kms:GenerateDataKey*",
                "kms:Encrypt"
            ],
            "Resource": "arn:aws:kms:your-region:your-account-id:key/your-kms-cmk-id",
            "Condition": {
                "StringLike": {
                    "kms:ViaService": [
                        "sqs.{your-region}.amazonaws.com",
                        "s3.{your-region}.amazonaws.com"
                    ]
                }
            }
        }
    ]
}

This policy grants Amazon MWAA the necessary permissions to interact with CloudWatch Logs, Amazon S3, Amazon SQS, and AWS KMS when using the AWS managed key offering, while explicitly specifying the resources it can access. You can further refine this policy based on your specific requirements.

The following is an example of an execution policy that allows Amazon MWAA to interact with various services using a KMS customer managed key:

{
    "Version": "2012-10-17",
    "Statement": [
        { 
            "Effect": "Deny",
            "Action": "s3:ListAllMyBuckets",
            "Resource": [
                "arn:aws:s3:::{your-s3-bucket-name}",
                "arn:aws:s3:::{your-s3-bucket-name}/*"
            ]
        }, 
        { 
            "Effect": "Allow",
            "Action": [ 
                "s3:GetObject*",
                "s3:GetBucket*",
                "s3:List*"
            ],
            "Resource": [
                "arn:aws:s3:::{your-s3-bucket-name}",
                "arn:aws:s3:::{your-s3-bucket-name}/*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "logs:CreateLogStream",
                "logs:CreateLogGroup",
                "logs:PutLogEvents",
                "logs:GetLogEvents",
                "logs:GetLogRecord",
                "logs:GetLogGroupFields",
                "logs:GetQueryResults"
            ],
            "Resource": [
                "arn:aws:logs:{your-region}:{your-account-id}:log-group:airflow-{your-environment-name}-*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "logs:DescribeLogGroups"
            ],
            "Resource": [
                "*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "s3:GetAccountPublicAccessBlock"
            ],
            "Resource": [
                "*"
            ]
        },
        {
            "Effect": "Allow",
            "Action": "cloudwatch:PutMetricData",
            "Resource": "*"
        },
        {
            "Effect": "Allow",
            "Action": [
                "sqs:ChangeMessageVisibility",
                "sqs:DeleteMessage",
                "sqs:GetQueueAttributes",
                "sqs:GetQueueUrl",
                "sqs:ReceiveMessage",
                "sqs:SendMessage"
            ],
            "Resource": "arn:aws:sqs:{your-region}:*:airflow-celery-*"
        },
        {
            "Effect": "Allow",
            "Action": [
                "kms:Decrypt",
                "kms:DescribeKey",
                "kms:GenerateDataKey*",
                "kms:Encrypt"
            ],
            "Resource": "arn:aws:kms:{your-region}:{your-account-id}:key/{your-kms-cmk-id}",
            "Condition": {
                "StringLike": {
                    "kms:ViaService": [
                        "sqs.{your-region}.amazonaws.com",
                        "s3.{your-region}.amazonaws.com"
                    ]
                }
            }
        }
    ]
}

For the use case of using the customer managed key, attach the following JSON policy to the key to provide access to the Airflow logs in CloudWatch Logs:

{
    "Sid": "Allow logs access",
    "Effect": "Allow",
    "Principal": {
        "Service": "logs.{your-region}.amazonaws.com"
    },
    "Action": [
        "kms:Encrypt*",
        "kms:Decrypt*",
        "kms:ReEncrypt*",
        "kms:GenerateDataKey*",
        "kms:Describe*"
    ],
    "Resource": "*",
    "Condition": {
        "ArnLike": {
            "kms:EncryptionContext:aws:logs:arn": "arn:aws:logs:{your-region}:{your-account-id}:*"
        }
    }
}

You can attach multiple policies to the execution role as needed to allow your workers to access additional AWS resources. For example, let’s explore how to enable Amazon EMR access. You can create a JSON policy that contains the narrowest permissions you can configure, as in the following example:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "elasticmapreduce:DescribeStep",
                "elasticmapreduce:AddJobFlowSteps",
                "elasticmapreduce:RunJobFlow"
            ],
            "Resource": "arn:aws:elasticmapreduce:*:xxxxxxxxxxxx:cluster/*"
        },
        {
            "Effect": "Allow",
            "Action": "iam:PassRole",
            "Resource": [
                "arn:aws:iam::xxxxxxxxxxxx:role/EMR_EC2_DefaultRole",
                "arn:aws:iam::xxxxxxxxxxxx:role/EMR_DefaultRole"
            ]
        }
    ]
}

Conclusion

In this post, we discussed best practices for least privilege configuration in Amazon MWAA. By following these approaches, you can adhere to the principle of least privilege and maintain a secure posture within your Amazon MWAA environment, without compromising functionality or relying on overly permissive policies. Security is always top priority; to learn more about security in Amazon MWAA, see Security in Amazon Managed Workflows for Apache Airflow and Security best practices on Amazon MWAA.


About the Authors

elizaws-headshotElizabeth Davis is a Sr Solutions Architect at Amazon Web Services (AWS). She currently works with educational technology companies and has a passion for serverless and data orchestration technologies. She has been an Amazon MWAA as a subject matter expert (SME) for the last 3+ years.

mark headshotMark Richman is a Principal Solutions Architect at Amazon Web Services with 30 years of experience building complex web and enterprise software. He contributes to Apache Airflow, bringing his expertise in cloud computing and serverless technologies to the open-source platform. Mark is also an accomplished writer and speaker who has authored commercial publications and AWS courses while regularly presenting at industry events.

Manage concurrent write conflicts in Apache Iceberg on the AWS Glue Data Catalog

Post Syndicated from Sotaro Hikita original https://aws.amazon.com/blogs/big-data/manage-concurrent-write-conflicts-in-apache-iceberg-on-the-aws-glue-data-catalog/

In modern data architectures, Apache Iceberg has emerged as a popular table format for data lakes, offering key features including ACID transactions and concurrent write support. Although these capabilities are powerful, implementing them effectively in production environments presents unique challenges that require careful consideration.

Consider a common scenario: A streaming pipeline continuously writes data to an Iceberg table while scheduled maintenance jobs perform compaction operations. Although Iceberg provides built-in mechanisms to handle concurrent writes, certain conflict scenarios—such as between streaming updates and compaction operations—can lead to transaction failures that require specific handling patterns.

This post demonstrates how to implement reliable concurrent write handling mechanisms in Iceberg tables. We will explore Iceberg’s concurrency model, examine common conflict scenarios, and provide practical implementation patterns of both automatic retry mechanisms and situations requiring custom conflict resolution logic for building resilient data pipelines. We will also cover the pattern with automatic compaction through AWS Glue Data Catalog table optimization.

Common conflict scenarios

The most frequent data conflicts occur in several specific operational scenarios that many organizations encounter in their data pipelines, which we discuss in this section.

Concurrent UPDATE/DELETE on overlapping partitions

When multiple processes attempt to modify the same partition simultaneously, data conflicts can arise. For example, imagine a data quality process updating customer records with corrected addresses while another process is deleting outdated customer records. Both operations target the same partition based on customer_id, leading to potential conflicts because they’re modifying an overlapping dataset. These conflicts are particularly common in large-scale data cleanup operations.

Compaction vs. streaming writes

A classic conflict scenario occurs during table maintenance operations. Consider a streaming pipeline ingesting real-time event data while a scheduled compaction job runs to optimize file sizes. The streaming process might be writing new records to a partition while the compaction job is attempting to combine existing files in the same partition. This scenario is especially common with Data Catalog table optimization, where automatic compaction can run concurrently with continuous data ingestion.

Concurrent MERGE operations

MERGE operations are particularly susceptible to conflicts because they involve both reading and writing data. For instance, an hourly job might be merging customer profile updates from a source system while a separate job is merging preference updates from another system. If both jobs attempt to modify the same customer records, they can conflict because each operation bases its changes on a different view of the current data state.

General concurrent table updates

When multiple transactions occur simultaneously, some transactions might fail to commit to the catalog due to interference from other transactions. Iceberg has mechanisms to handle this scenario, so it can adapt to concurrent transactions in many cases. However, commits can still fail if the latest metadata is updated after the base metadata version is established. This scenario applies to any type of updates on an Iceberg table.

Iceberg’s concurrency model and conflict type

Before diving into specific implementation patterns, it’s essential to understand how Iceberg manages concurrent writes through its table architecture and transaction model. Iceberg uses a layered architecture to manage table state and data:

  • Catalog layer – Maintains a pointer to the current table metadata file, serving as the single source of truth for table state. The Data Catalog provides the functionality as the Iceberg catalog.
  • Metadata layer – Contains metadata files that track table history, schema evolution, and snapshot information. These files are stored on Amazon Simple Storage Service (Amazon S3).
  • Data layer – Stores the actual data files and delete files (for Merge-on-Read operations). These files are also stored on Amazon S3.

The following diagram illustrates this architecture.

This architecture is fundamental to Iceberg’s optimistic concurrency control, where multiple writers can proceed with their operations simultaneously, and conflicts are detected at commit time.

Write transaction flow

A typical write transaction in Iceberg follows these key steps:

  1. Read current state. In many operations (like OVERWRITE, MERGE, and DELETE), the query engine needs to know which files or rows are relevant, so it reads the current table snapshot. This is optional for operations like INSERT.
  2. Determine the changes in transaction, and write new data files.
  3. Load the table’s latest metadata, and determine which metadata version is used as the base for the update.
  4. Check if the change prepared in Step 2 is compatible with the latest table data in Step 3. If the check failed, the transaction must stop.
  5. Generate new metadata files.
  6. Commit the metadata files to the catalog. If the commit failed, retry from Step 3. The number of retries depends on the configuration.

The following diagram illustrates this workflow.

Iceberg write transaction flow

Conflicts can occur at two critical points:

  • Data update conflicts – During validation when checking for data conflicts (Step 4)
  • Catalog commit conflicts – During the commit when attempting to update the catalog pointer (Step 6)

When working with Iceberg tables, understanding the types of conflicts that can occur and how they’re handled is crucial for building reliable data pipelines. Let’s examine the two primary types of conflicts and their characteristics.

Catalog commit conflicts

Catalog commit conflicts occur when multiple writers attempt to update the table metadata simultaneously. When a commit conflict occurs, Iceberg will automatically retry the operation based on the table’s write properties. The retry process only repeats the metadata commit, not the entire transaction, making it both safe and efficient. When the retries fail, the transaction fails with CommitFailedException.

In the following diagram, two transactions run concurrently. Transaction 1 successfully updates the table’s latest snapshot in the Iceberg catalog from 0 to 1. Meanwhile, transaction 2 attempts to update from Snapshot 0 to 1, but when it tries to commit the changes to the catalog, it finds that the latest snapshot has already been changed to 1 by transaction 1. As a result, transaction 2 needs to retry from Step 3.

Catalog commit conflicts1

These conflicts are typically transient and can be automatically resolved through retries. You can optionally configure write properties controlling commit retry behavior. For more detailed configuration, refer to Write properties in the Iceberg documentation.

The metadata used when reading the current state (Step 1) and the snapshot used as base metadata for updates (Step 3) can be different. Even if another transaction updates the latest snapshot between Steps 1 and 3, the current transaction can still commit changes to the catalog as long as it passes the data conflict check (Step 4). This means that even when computing changes and writing data files (Step 1 to 2) take a long time, and other transactions make changes during this period, the transaction can still attempt to commit to the catalog. This demonstrates Iceberg’s intelligent concurrency control mechanism.

The following diagram illustrates this workflow.

Catalog commit conflicts2

Data update conflicts

Data update conflicts are more complex and occur when concurrent transactions attempt to modify overlapping data. During a write transaction, the query engine checks consistency between the snapshot being written and the latest snapshot according to transaction isolation rules. When incompatibility is detected, the transaction fails with a ValidationException.

In the following diagram, two transactions run concurrently on an employee table containing id, name, and salary columns. Transaction 1 attempts to update a record based on Snapshot 0 and successfully commits this change, making the latest snapshot version 1. Meanwhile, transaction 2 also attempts to update the same record based on Snapshot 0. When transaction 2 initially scanned the data, the latest snapshot was 0, but it has since been updated to 1 by transaction 1. During the data conflict check, transaction 2 discovers that its changes conflict with Snapshot 1, resulting in the transaction failing.

data conflict

These conflicts can’t be automatically retried by Iceberg’s library because when data conflicts occur, the table’s state has changed, making it uncertain whether retrying the transaction would maintain overall data consistency. You need to handle this type of conflict based on your specific use case and requirements.

The following table summarizes how different write patterns have varying likelihood of conflicts.

Write Pattern Catalog Commit Conflict (Automatically retryable) Data Conflict (Non-retryable)
INSERT (AppendFiles) Yes Never
UPDATE/DELETE with Copy-on-Write or Merge-on-Read (OverwriteFiles) Yes Yes
Compaction (RewriteFiles) Yes Yes

Iceberg table’s isolation levels

Iceberg tables support two isolation levels: Serializable and Snapshot isolation. Both provide a read consistent view of the table and ensure readers see only committed data. Serializable isolation guarantees that concurrent operations run as if they were performed in some sequential order. Snapshot isolation provides weaker guarantees but offers better performance in environments with many concurrent writers. Under snapshot isolation, data conflict checks can pass even when concurrent transactions add new files with records that potentially match its conditions.

By default, Iceberg tables use serializable isolation. You can configure isolation levels for specific operations using table properties:

tbl_properties = {
    'write.delete.isolation-level' = 'serializable',
    'write.update.isolation-level' = 'serializable',
    'write.merge.isolation-level' = 'serializable'
}

You must choose the appropriate isolation level based on your use case. Note that for conflicts between streaming ingestion and compaction operations, which is one of the most common scenarios, snapshot isolation does not provide any additional benefits to the default serializable isolation. For more detailed configuration, see IsolationLevel.

Implementation patterns

Implementing robust concurrent write handling in Iceberg requires different strategies depending on the conflict type and use case. In this section, we share proven patterns for handling common scenarios.

Manage catalog commit conflicts

Catalog commit conflicts are relatively straightforward to handle through table properties. The following configurations serve as initial baseline settings that you can adjust based on your specific workload patterns and requirements.

For frequent concurrent writes (for example, streaming ingestion):

tbl_properties = {
    'commit.retry.num-retries': '10',
    'commit.retry.min-wait-ms': '100',
    'commit.retry.max-wait-ms': '10000',
    'commit.retry.total-timeout-ms': '1800000'
}

For maintenance operations (for example, compaction):

tbl_properties = {
    'commit.retry.num-retries': '4',
    'commit.retry.min-wait-ms': '1000',
    'commit.retry.max-wait-ms': '60000',
    'commit.retry.total-timeout-ms': '1800000'
}

Manage data update conflicts

For data update conflicts, which can’t be automatically retried, you need to implement a custom retry mechanism with proper error handling. A common scenario is when stream UPSERT ingestion conflicts with concurrent compaction operations. In such cases, the stream ingestion job should typically implement retries to handle incoming data. Without proper error handling, the job will fail with a ValidationException.

We show two example scripts demonstrating a practical implementation of error handling for data conflicts in Iceberg streaming jobs. The code specifically catches ValidationException through Py4JJavaError handling, which is essential for proper Java-Python interaction. It includes exponential backoff and jitter strategy by adding a random delay of 0–25% to each retry interval. For example, if the base exponential backoff time is 4 seconds, the actual retry delay will be between 4–5 seconds, helping prevent immediate retry storms while maintaining reasonable latency.

In this example, we create a scenario with frequent MERGE operations on the same records by using 'value' as a unique identifier and artificially limiting its range. By applying a modulo operation (value % 20), we constrain all values to fall within 0–19, which means multiple updates will target the same records. For instance, if the original stream contains values 0, 20, 40, and 60, they will all be mapped to 0, resulting in multiple MERGE operations targeting the same record. We then use groupBy and max aggregation to simulate a typical UPSERT pattern where we keep the latest record for each value. The transformed data is stored in a temporary view that serves as the source table in the MERGE statement, allowing us to perform UPDATE operations using 'value' as the matching condition. This setup helps demonstrate how our retry mechanism handles ValidationExceptions that occur when concurrent transactions attempt to modify the same records.

The first example uses Spark Structured Streaming using a rate source with a 20-second trigger interval to demonstrate the retry mechanism’s behavior when concurrent operations cause data conflicts. Replace <database_name> with your database name, <table_name> with your table name, amzn-s3-demo-bucket with your S3 bucket name.

import time
import random
from pyspark.sql import SparkSession
from py4j.protocol import Py4JJavaError
from pyspark.sql.functions import max as max_

CATALOG = "glue_catalog"
DATABASE = "<database_name>"
TABLE = "<table_name>"
BUCKET = "amzn-s3-demo-bucket"

spark = SparkSession.builder \
    .appName("IcebergUpsertExample") \
    .config(f"spark.sql.catalog.{CATALOG}", "org.apache.iceberg.spark.SparkCatalog") \
    .config("spark.sql.extensions","org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions") \
    .config(f"spark.sql.catalog.{CATALOG}.io-impl","org.apache.iceberg.aws.s3.S3FileIO") \
    .config("spark.sql.defaultCatalog", CATALOG) \
    .config(f"spark.sql.catalog.{CATALOG}.type", "glue") \
    .getOrCreate()
    
spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {DATABASE}.{TABLE} (
        timestamp TIMESTAMP,
        value LONG
    )
    USING iceberg
    LOCATION 's3://{BUCKET}/warehouse'
""")

def backoff(attempt):
    """Exponential backoff with jitter"""
    exp_backoff = min(2 ** attempt, 60)
    jitter = random.uniform(0, 0.25 * exp_backoff)
    return exp_backoff + jitter

def is_validation_exception(java_exception):
    """Check if exception is ValidationException"""
    cause = java_exception
    while cause is not None:
        if "org.apache.iceberg.exceptions.ValidationException" in str(cause.getClass().getName()):
            return True
        cause = cause.getCause()
    return False

def upsert_with_retry(microBatchDF, batchId):
    max_retries = 5
    attempt = 0
    
    # Use a narrower key range to intentionally increase updates for the same value in MERGE
    transformedDF = microBatchDF \
        .selectExpr("timestamp", "value % 20 AS value") \
        .groupBy("value") \
        .agg(max_("timestamp").alias("timestamp"))
        
    view_name = f"incoming_data_{batchId}"
    transformedDF.createOrReplaceGlobalTempView(view_name)
    
    while attempt < max_retries:
        try:
            spark.sql(f"""
                MERGE INTO {DATABASE}.{TABLE} AS t
                USING global_temp.{view_name} AS i
                ON t.value = i.value
                WHEN MATCHED THEN
                  UPDATE SET
                    t.timestamp = i.timestamp,
                    t.value     = i.value
                WHEN NOT MATCHED THEN
                  INSERT (timestamp, value)
                  VALUES (i.timestamp, i.value)
            """)
            
            print(f"[SUCCESS] Batch {batchId} processed successfully")
            return
            
        except Py4JJavaError as e:
            if is_validation_exception(e.java_exception):
                attempt += 1
                if attempt < max_retries:
                    delay = backoff(attempt)
                    print(f"[RETRY] Batch {batchId} failed with ValidationException. "
                          f"Retrying in {delay} seconds. Attempt {attempt}/{max_retries}")
                    time.sleep(delay)
                else:
                    print(f"[FAILED] Batch {batchId} failed after {max_retries} attempts")
                    raise

# Sample streaming query setup
df = spark.readStream \
    .format("rate") \
    .option("rowsPerSecond", 10) \
    .load()

# Start streaming query
query = df.writeStream \
    .trigger(processingTime="20 seconds") \
    .option("checkpointLocation", f"s3://{BUCKET}/checkpointLocation") \
    .foreachBatch(upsert_with_retry) \
    .start()

query.awaitTermination()

The second example uses GlueContext.forEachBatch available on AWS Glue Streaming jobs. The implementation pattern for the retry mechanism remains the same, but the main differences are the initial setup using GlueContext and how to create a streaming DataFrame. Although our example uses spark.readStream with a rate source for demonstration, in actual AWS Glue Streaming jobs, you would typically create your streaming DataFrame using glueContext.create_data_frame.from_catalog to read from sources like Amazon Kinesis or Kafka. For more details, see AWS Glue Streaming connections. Replace <database_name> with your database name, <table_name> with your table name, amzn-s3-demo-bucket with your S3 bucket name.

import time
import random
from py4j.protocol import Py4JJavaError
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from pyspark.sql import SparkSession
from pyspark.sql.functions import max as max_

CATALOG = "glue_catalog"
DATABASE = "<database_name>"
TABLE = "<table_name>"
BUCKET = "amzn-s3-demo-bucket"

spark = SparkSession.builder \
    .appName("IcebergUpsertExample") \
    .config(f"spark.sql.catalog.{CATALOG}", "org.apache.iceberg.spark.SparkCatalog") \
    .config("spark.sql.extensions","org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions") \
    .config(f"spark.sql.catalog.{CATALOG}.io-impl","org.apache.iceberg.aws.s3.S3FileIO") \
    .config("spark.sql.defaultCatalog", CATALOG) \
    .config(f"spark.sql.catalog.{CATALOG}.type", "glue") \
    .getOrCreate()

sc = spark.sparkContext
glueContext = GlueContext(sc)

spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {DATABASE}.{TABLE} (
        timestamp TIMESTAMP,
        value LONG
    )
    USING iceberg
    LOCATION 's3://{BUCKET}/warehouse'
""")

def backoff(attempt):
    exp_backoff = min(2 ** attempt, 60)
    jitter = random.uniform(0, 0.25 * exp_backoff)
    return exp_backoff + jitter

def is_validation_exception(java_exception):
    cause = java_exception
    while cause is not None:
        if "org.apache.iceberg.exceptions.ValidationException" in str(cause.getClass().getName()):
            return True
        cause = cause.getCause()
    return False

def upsert_with_retry(batch_df, batchId):
    max_retries = 5
    attempt = 0
    transformedDF = batch_df.selectExpr("timestamp", "value % 20 AS value") \
                           .groupBy("value") \
                           .agg(max_("timestamp").alias("timestamp"))
                           
    view_name = f"incoming_data_{batchId}"
    transformedDF.createOrReplaceGlobalTempView(view_name)
    
    while attempt < max_retries:
        try:
            spark.sql(f"""
                MERGE INTO {DATABASE}.{TABLE} AS t
                USING global_temp.{view_name} AS i
                ON t.value = i.value
                WHEN MATCHED THEN
                  UPDATE SET
                    t.timestamp = i.timestamp,
                    t.value     = i.value
                WHEN NOT MATCHED THEN
                  INSERT (timestamp, value)
                  VALUES (i.timestamp, i.value)
            """)
            print(f"[SUCCESS] Batch {batchId} processed successfully")
            return
        except Py4JJavaError as e:
            if is_validation_exception(e.java_exception):
                attempt += 1
                if attempt < max_retries:
                    delay = backoff(attempt)
                    print(f"[RETRY] Batch {batchId} failed with ValidationException. "
                          f"Retrying in {delay} seconds. Attempt {attempt}/{max_retries}")
                    time.sleep(delay)
                else:
                    print(f"[FAILED] Batch {batchId} failed after {max_retries} attempts")
                    raise

# Sample streaming query setup
streaming_df = spark.readStream \
    .format("rate") \
    .option("rowsPerSecond", 10) \
    .load()

# In actual Glue Streaming jobs, you would typically create a streaming DataFrame like this:
"""
streaming_df = glueContext.create_data_frame.from_catalog(
    database = "database",
    table_name = "table_name",
    transformation_ctx = "streaming_df",
    additional_options = {
        "startingPosition": "TRIM_HORIZON",
        "inferSchema": "false"
    }
)
"""

glueContext.forEachBatch(
    frame=streaming_df,
    batch_function=upsert_with_retry,
    options={
        "windowSize": "20 seconds",
        "checkpointLocation": f"s3://{BUCKET}/checkpointLocation"
    }
)

Minimize conflict possibility by scoping your operations

When performing maintenance operations like compaction or updates, it’s recommended to narrow down the scope to minimize overlap with other operations. For example, consider a table partitioned by date where a streaming job continuously upserts data for the latest date. The following is the example script to run the rewrite_data_files procedure to compact the entire table:

# Example of broad scope compaction
spark.sql("""
   CALL catalog_name.system.rewrite_data_files(
       table => 'db.table_name'
   )
""")

By narrowing the compaction scope with a date partition filter in the where clause, you can avoid conflicts between streaming ingestion and compaction operations. The streaming job can continue to work with the latest partition while compaction processes historical data.

# Narrow down the scope by partition
spark.sql("""
    CALL catalog_name.system.rewrite_data_files(
        table => 'db.table_name',
        where => 'date_partition < current_date'
    )
""")

Conclusion

Successfully managing concurrent writes in Iceberg requires understanding both the table architecture and various conflict scenarios. In this post, we explored how to implement reliable conflict handling mechanisms in production environments.

The most critical concept to remember is the distinction between catalog commit conflicts and data conflicts. Although catalog commit conflicts can be handled through automatic retries and table properties configuration, data conflicts require careful implementation of custom handling logic. This becomes particularly important when implementing maintenance operations like compaction, where using the where clause in rewrite_data_files can significantly minimize conflict potential by reducing the scope of operations.

For streaming pipelines, the key to success lies in implementing proper error handling that can differentiate between conflict types and respond appropriately. This includes configuring suitable retry settings through table properties and implementing backoff strategies that align with your workload characteristics. When combined with well-timed maintenance operations, these patterns help build resilient data pipelines that can handle concurrent writes reliably.

By applying these patterns and understanding the underlying mechanisms of Iceberg’s concurrency model, you can build robust data pipelines that effectively handle concurrent write scenarios while maintaining data consistency and reliability.


About the Authors

Sotaro Hikita is an Analytics Solutions Architect. He supports customers across a wide range of industries in building and operating analytics platforms more effectively. He is particularly passionate about big data technologies and open source software.

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.

Ingest data from Google Analytics 4 and Google Sheets to Amazon Redshift using Amazon AppFlow

Post Syndicated from Ritesh Sinha original https://aws.amazon.com/blogs/big-data/ingest-data-from-google-analytics-4-and-google-sheets-to-amazon-redshift-using-amazon-appflow/

Google Analytics 4 (GA4) provides valuable insights into user behavior across websites and apps. But what if you need to combine GA4 data with other sources or perform deeper analysis? That’s where Amazon Redshift and Amazon AppFlow come in. Amazon AppFlow bridges the gap between Google applications and Amazon Redshift, empowering organizations to unlock deeper insights and drive data-informed decisions. In this post, we show you how to establish the data ingestion pipeline between Google Analytics 4, Google Sheets, and an Amazon Redshift Serverless workgroup.

Amazon AppFlow is a fully managed integration service that you can use to securely transfer data from software as a service (SaaS) applications, such as Google BigQuery, Salesforce, SAP, HubSpot, and ServiceNow, to Amazon Web Services (AWS) services such as Amazon Simple Storage Service (Amazon S3) and Amazon Redshift, in just a few clicks. With Amazon AppFlow, you can run data flows at nearly any scale and at the frequency you choose—on a schedule, in response to a business event, or on demand. You can configure data transformation capabilities such as filtering and validation to generate rich, ready-to-use data as part of the flow itself, without additional steps. Amazon AppFlow automatically encrypts data in motion, and allows you to restrict data from flowing over the public internet for SaaS applications that are integrated with AWS PrivateLink, reducing exposure to security threats.

Amazon Redshift is a fast, scalable, and fully managed cloud data warehouse that allows you to process and run your complex SQL analytics workloads on structured and semi-structured data. It also helps you securely access your data in operational databases, data lakes, or third-party datasets with minimal movement or copying of data. Tens of thousands of customers use Amazon Redshift to process large amounts of data, modernize their data analytics workloads, and provide insights for their business users.

Prerequisites

Before starting this walkthrough, you need to have the following prerequisites in place:

  • An AWS account.
  • In your Google Cloud project, you’ve enabled the following APIs:
    • Google Analytics API
    • Google Analytics Admin API
    • Google Analytics Data API
    • Google Sheets API
    • Google Drive API

For more information, refer to Amazon AppFlow support for Google Sheets.

For the steps to enable these APIs, see Enable and disable APIs on the API Console Help for Google Cloud Platform.

Architecture overview

The following architecture shows how Amazon AppFlow can transform and move data from SaaS applications to processing and storage destinations. Three sections appear from left to right in the diagram: Source, Move, Target. These sections are described in the following section.

  • Source – The leftmost section on the diagram represents different applications acting as a source, including Google Analytics, Google Sheets, and Google BigQuery.
  • Move – The middle section is labeled Amazon AppFlow. The section contains boxes that represent Amazon AppFlow operations such as Mask Fields, Map Fields, Merge Fields, Filter Data, and others. In this post, we focus on setting up the data movement using Amazon AppFlow and filtering data based on start date. The other transformation operations such as mapping, masking, and merging fields are not covered in this post.
  • Destination – The section on the right of the diagram is labeled Destination and represents targets such as Amazon Redshift and Amazon S3. In this psot, we primarily focus on Amazon Redshift as the destination.

This post has two parts. The first part covers integrating from Google Analytics. The second part focuses on connecting with Google Sheets.

Application configuration in Google Cloud Platform

Amazon AppFlow requires OAuth 2.0 for authentication. You need to create an OAuth 2.0 client ID, which Amazon AppFlow uses when requesting an OAuth 2.0 access token. To create an OAuth 2.0 client ID in the Google Cloud Platform console, follow these steps:

  1. On the Google Cloud Platform Console, from the projects list, select a project or create a new one.
  2. If the APIs & Services page isn’t already open, choose the menu icon on the upper left and select APIs & Services.
  3. In the navigation pane, choose Credentials.
  4. Choose CREATE CREDENTIALS, then choose OAuth client ID, as shown in the following screenshot.

  1. Select the application type Web application, enter the name demo-google-aws, and provide URIs for Authorized JavaScript origins https://console.aws.amazon.com. For Authorized redirect URIs, add https://us-east-1.console.aws.amazon.com/appflow/oauth. Choose SAVE, as shown in the following screenshot.

  1. The OAuth client ID is now created. Select demo-google-aws.

  1. Under Additional information, as shown in the following screenshot, note down the Client ID and Client secret.

Data ingestion from Google Analytics 4 to Amazon Redshift

In this section, you configure Amazon AppFlow to set up a connection between Google Analytics 4 and Amazon Redshift for data migration. This procedure can be classified into the following steps:

  1. Create a connection to Google Analytics 4 in Amazon AppFlow
  2. Create an IAM role for Amazon AppFlow integration with Amazon Redshift
  3. Set up Amazon AppFlow connection for Amazon Redshift
  4. Set up table and permission in Amazon Redshift
  5. Create data flow in Amazon AppFlow

Create a connection to Google Analytics 4 in Amazon AppFlow

To create a connection to Google Analytics 4 in Amazon AppFlow, follow these steps:

  1. Sign in to the AWS Management Console and open Amazon AppFlow.
  2. In the navigation pane on the left, choose Connections.
  3. On the Manage connections page, for Connectors, choose Google Analytics 4.
  4. Choose Create connection.
  5. In the Connect to Google Analytics 4 window, enter the following information. For Client ID, enter the client ID of the OAuth 2.0 client ID in your Google Cloud project created in the previous section. For Client secret, enter the client secret of the OAuth 2.0 client ID in your Google Cloud project created in the previous section.
  6. (Optional) under Data encryption, choose Customize encryption settings (advanced) if you want to encrypt your data with a customer managed key in AWS Key Management Service (AWS KMS). By default, Amazon AppFlow encrypts your data with an AWS KMS key that AWS creates, uses, and manages for you. Choose this option if you want to encrypt your data with your own AWS KMS key instead.

The following screenshot shows the Connect to Google Analytics 4 window.

Amazon AppFlow encrypts your data during transit and at rest. For more information, see Data protection in Amazon AppFlow.

If you want to use an AWS KMS key from the current AWS account, select this key under Choose an AWS KMS key. If you want to use an AWS KMS key from a different AWS account, enter the Amazon Resource Name (ARN) for that key:

  1. For Connection name, enter a name for your connection
  2. Choose Continue
  3. In the window that appears, sign in to your Google account and grant access to Amazon AppFlow

On the Manage connections page, your new connection appears in the Connections table. When you create a flow that uses Google Analytics 4 as the data source, you can select this connection.

Create an IAM role for Amazon AppFlow integration with Amazon Redshift

You can use Amazon AppFlow to transfer data from supported sources into your Amazon Redshift databases. You need an IAM role because Amazon AppFlow needs authorization to access Amazon Redshift using an Amazon Redshift Data API.

  1. Sign in to the AWS Management Console, preferably as admin user, and in the navigation pane of the IAM dashboard, choose Policies.
  2. Choose Create policy.
  3. Select the JSON tab and paste in the following policy. Amazon AppFlow needs the following permissions to gain access and run SQL statements with the Amazon Redshift database.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DataAPIPermissions",
      "Effect": "Allow",
      "Action": [
        "redshift-data:ExecuteStatement",
        "redshift-data:GetStatementResult",
        "redshift-data:DescribeStatement"
      ],
      "Resource": "*"
    },
    {
      "Sid": "GetCredentialsForAPIUser",
      "Effect": "Allow",
      "Action": "redshift:GetClusterCredentials",
      "Resource": [
        "arn:aws:redshift:*:*:dbname:*/*",
        "arn:aws:redshift:*:*:dbuser:*/*"
      ]
    },
    {
      "Sid": "GetCredentialsForServerless",
      "Effect": "Allow",
      "Action": "redshift-serverless:GetCredentials",
      "Resource": "*"
    },
    {
      "Sid": "DenyCreateAPIUser",
      "Effect": "Deny",
      "Action": "redshift:CreateClusterUser",
      "Resource": [
        "arn:aws:redshift:*:*:dbuser:*/*"
      ]
    },
    {
      "Sid": "ServiceLinkedRole",
      "Effect": "Allow",
      "Action": "iam:CreateServiceLinkedRole",
      "Resource": "arn:aws:iam::*:role/aws-service-role/redshift-data.amazonaws.com/AWSServiceRoleForRedshift",
      "Condition": {
        "StringLike": {
          "iam:AWSServiceName": "redshift-data.amazonaws.com"
        }
      }
    }
  ]
}
  1. Choose Next, provide the Policy name as appflow-redshift-policy, Description as appflow redshift policy, and choose Create policy.

  1. In the navigation pane, choose Roles and Create role. Choose Custom trust policy and paste in the following. Choose Next. This trust policy grants Amazon AppFlow the ability to assume the role for Amazon AppFlow to access and process data.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "Service": "appflow.amazonaws.com"
      },
      "Action": "sts:AssumeRole"
    }
  ]
}
  1. Search for policy appflow-redshift-policy, check the box next to it, and choose Next.

  1. Provide the role name appflow-redshift-access-role and Description and choose Create role.

Set up Amazon AppFlow connection for Amazon Redshift

To set up an Amazon AppFlow connection for Amazon Redshift, follow these steps:

  1. On the Amazon AppFlow console, in the navigation pane, choose Connectors, select Amazon Redshift, and choose Create connection.

  1. Enter the connection name appflow-redshift-connection. You can either use Amazon Redshift provisioned or Amazon Redshift Serverless, but in this example we are using Amazon Redshift Serverless. Select Amazon Redshift Serverless and enter the workgroup name and database name.
  2. Choose the S3 bucket and enter the bucket prefix.

  1. For Amazon S3 access, select the IAM role attached to the Redshift cluster or namespace during the creation of the Redshift cluster. Additionally, for the Amazon Redshift Data API, choose the IAM role appflow-redshift-access-role created in the previous section and then choose

Set up a table and permission in Amazon Redshift

To set up table and permission in Amazon Redshift, follow these steps:

  1. On the Amazon Redshift console, choose Query editor v2 in Explorer.
  2. Connect to your existing Redshift cluster or Amazon Redshift Serverless workgroup.
  3. Create a table with the following Data Definition Language (DDL).
create table public.stg_ga4_daily_summary

(

event_date date,

region varchar(255),

country varchar(255),

city varchar(255),

deviceCategory varchar(255),

deviceModel varchar(255),

browser varchar(255),

active_users INTEGER,

new_users integer,

total_revenue  NUMERIC(18,2)

);

The following screenshot shows the successful creation of this table in Amazon Redshift:

The following step is only applicable to Amazon Redshift Serverless. If you are using a Redshift provisioned cluster, you can skip this step.

  1. Grant the permissions on the table to the IAM user used by Amazon AppFlow to load data into Amazon Redshift Serverless, for example, appflow-redshift-access-role.
GRANT INSERT ON TABLE public.stg_ga4_daily_summary TO "IAMR:appflow-redshift-access-role";

Create data flow in Amazon AppFlow

To create a data flow in Amazon AppFlow, follow these steps:

  1. On the Amazon AppFlow console, choose Flows and select Amazon Redshift. Choose Create flow and enter the flow name and the flow description, as shown in the following screenshot.

  1. In Source name, choose Google Analytics 4. Choose the Google Analytics 4 connection.
  2. Select the Google Analytics 4 object, then choose Amazon Redshift as the destination, selecting the public schema and stg_ga4_daily_summary table in your Redshift instance.

  1. For Flow trigger, choose Run on demand and choose Next, as shown in the following screenshot.

You can run the flow on schedule to pull either full or incremental data refresh. For more information, see Schedule-triggered flows.

  1. Select Manually map fields. From the Source field name dropdown menu, select the attribute date, and from the Destination field name, select event_date and choose Map fields, as shown in the following screenshot.

  1. Repeat the previous step (step 5) for the following attributes and then choose Next. The following screenshot shows the mapping.
Dimension:browser --> browser
Dimension:region --> region
Dimension:country --> country
Dimension:city --> city
Dimension:deviceCategory --> devicecategory
Dimension:deviceModel --> devicemodel
Metric:activeUsers --> active_users
Metric:newUsers --> new_users
Metric: totalRevenue --> total_revenue
Dimension:date --> event_date

The Google Analytics API provides various dimensions and metrics for reporting purposes. Refer to API Dimensions & Metrics for details.

  1. In Field name, enter the filter start_end_date and choose Next, as shown in the following screenshot. The Amazon AppFlow date filter supports both a start date (criteria1) and an end date (criteria2) to define the desired date range for data transfer. We are using the date range because we have sample data created for this range.

  1. Review the configurations and choose Create flow.
  2. Choose Run flow, as shown in the following screenshot, and wait for the flow execution to be completed.

  1. On the Amazon Redshift console, choose Query editor v2 in Explorer.
  2. Connect to your existing Redshift cluster or Amazon Redshift Serverless workgroup.
  3. Enter the following SQL to verify the data in Amazon Redshift.
select * from public.stg_ga4_daily_summary

The screenshot below shows the results loaded into the stg_ga4_daily_summary table.

Data ingestion from Google Sheets to Amazon Redshift

Ingesting data from Google Sheets to Amazon Redshift using Amazon AppFlow streamlines analytics, enabling seamless transfer and deeper insights. In this section, we demonstrate how business users can maintain their business glossary in Google Sheets and integrate that using Amazon AppFlow with Amazon Redshift and get meaningful insights.

For this demo, you can upload the Nation Market segment file to your Google sheet before proceeding to the next steps. These steps show how to configure Amazon AppFlow to set up a connection between Google Sheets and Amazon Redshift for data migration. This procedure can be classified into the following steps:

  1. Create Google Sheets connection in Amazon AppFlow
  2. Set up table and permission in Amazon Redshift
  3. Create data flow in Amazon AppFlow

Create Google Sheets connection in Amazon AppFlow

To create a Google Sheets connection in Amazon AppFlow, follow these steps:

  1. On the Amazon AppFlow console, choose Connectors, select Google Sheets, then choose Create connection.
  2. In the Connect to Google Sheets window, enter the following information. For Client ID, enter the client ID of the OAuth 2.0 client ID in your Google Sheets project. For Client secret, enter the client secret of the OAuth 2.0 client ID in your Google Sheets project.
  3. For Connection name, enter a name for your connection.
  4. (Optional) Under Data encryption, choose Customize encryption settings (advanced) if you want to encrypt your data with a customer managed key in AWS KMS. By default, Amazon AppFlow encrypts your data with an AWS KMS key that AWS creates, uses, and manages for you. Choose this option if you want to encrypt your data with your own AWS KMS key instead.
  5. Choose Connect.
  6. In the window that appears, sign in to your Google account and grant access to Amazon AppFlow.

Set up table and permission in Amazon Redshift

To set up a table and permission in Amazon Redshift, follow these steps:

  1. On the Amazon Redshift console, choose Query editor v2 in Explorer
  2. Connect to your existing Redshift cluster or Amazon Redshift Serverless workgroup
  3. Create a table with the following DDL
create table public.stg_nation_market_segment(
n_nationkey int4 not null,
n_name char(25) not null ,
n_regionkey int4 not null,
n_comment varchar(152) not null,
n_marketsegment varchar(255),
Primary Key(N_NATIONKEY)
) distkey(n_nationkey) sortkey(n_nationkey);

he following steps are only applicable to Amazon Redshift Serverless. If you are using a Redshift provisioned cluster, you can skip this step.

  1. Grant the permissions on the table to the IAM user used by Amazon AppFlow to load data into Amazon Redshift Serverless, for example, appflow-redshift-access-role
GRANT INSERT ON TABLE public.stg_nation_market_segment TO "IAMR:appflow-redshift-access-role";

Create data flow in Amazon AppFlow

  1. On the Amazon AppFlow console, choose Flows and select Google Sheets. Choose Create flow, enter the flow name and flow description, and choose Next.
  2. Select Google Sheets in Source name and choose the Google Sheets connection.
  3. Select the Google Sheets object nation_market_segment#Sheet1.
  4. Choose the Destination name as Amazon Redshift, then select stg_nation_market_segment as your Amazon Redshift object, as shown in the following screenshot.

  1. For Flow trigger, select On demand and choose Next.

You can run the flow on schedule to pull full or incremental data refresh. Read more at Schedule-triggered flows.

  1. Select Manually map fields. From the Source field name dropdown menu, select Map all fields directly. When a dialog box pops up, choose the respective attribute values and choose Map fields, as shown in the following screenshot. Choose Next.

The following screenshot shows the mapping.

  1. On the Add Filters page, choose Next.
  2. On the Review and create page, choose Create flow.
  3. Choose Run flow and wait for the flow execution to finish.

The screenshot below shows the execution details of the flow job.

  1. On the Amazon Redshift console, choose Query editor v2 in Explorer.
  2. Connect to your existing Redshift cluster or Amazon Redshift Serverless workgroup.
  3. Run the following SQL to verify the data in Amazon Redshift.
select * from public.stg_nation_market_segment

The screenshot below shows the results loaded into the stg_nation_market_segment table.

  1. Run the following SQL to prepare a sample dataset in Amazon Redshift.
create table public.customer (
c_custkey int8 not null ,
c_name varchar(25) not null,
c_address varchar(40) not null,
c_nationkey int4 not null,
c_phone char(15) not null,
c_acctbal numeric(12,2) not null,
c_mktsegment char(10) not null,
c_comment varchar(117) not null,
Primary Key(C_CUSTKEY)
) distkey(c_custkey) sortkey(c_custkey);

create table public.lineitem (
l_orderkey int8 not null ,
l_partkey int8 not null,
l_suppkey int4 not null,
l_linenumber int4 not null,
l_quantity numeric(12,2) not null,
l_extendedprice numeric(12,2) not null,
l_discount numeric(12,2) not null,
l_tax numeric(12,2) not null,
l_returnflag char(1) not null,
l_linestatus char(1) not null,
l_shipdate date not null ,
l_commitdate date not null,
l_receiptdate date not null,
l_shipinstruct char(25) not null,
l_shipmode char(10) not null,
l_comment varchar(44) not null,
Primary Key(L_ORDERKEY, L_LINENUMBER)
) distkey(l_orderkey) sortkey(l_shipdate,l_orderkey)  ;

create table public.orders (
o_orderkey int8 not null,
o_custkey int8 not null,
o_orderstatus char(1) not null,
o_totalprice numeric(12,2) not null,
o_orderdate date not null,
o_orderpriority char(15) not null,
o_clerk char(15) not null,
o_shippriority int4 not null,
o_comment varchar(79) not null,
Primary Key(O_ORDERKEY)
) distkey(o_orderkey) sortkey(o_orderdate, o_orderkey) ;
copy lineitem from 's3://redshift-downloads/TPC-H/2.18/10GB/lineitem.tbl' iam_role default delimiter '|' region 'us-east-1';
copy orders from 's3://redshift-downloads/TPC-H/2.18/10GB/orders.tbl' iam_role default delimiter '|' region 'us-east-1';
copy customer from 's3://redshift-downloads/TPC-H/2.18/10GB/customer.tbl' iam_role default delimiter '|' region 'us-east-1';
  1. Run the following SQL to do the data analytics using Google Sheets business data classification in the Amazon Redshift dataset.
select
n_marketsegment,
sum(l_extendedprice * (1 - l_discount)) as revenue
from
public.customer,
public.orders,
public.lineitem,
public.stg_nation_market_segment
where
c_custkey = o_custkey
and l_orderkey = o_orderkey
and c_nationkey = n_nationkey
group by
1
order by
revenue desc;

The screenshot below shows the results from the aggregated query in Amazon Redshift from data loaded using Amazon Appflow.

Clean up

To avoid incurring charges, clean up the resources in your AWS account by completing the following steps:

  1. On the Amazon AppFlow console, in the navigation pane, choose Flows.
  2. From the list of flows, select the flow name created and delete it.
  3. Enter “delete” to delete the flow.
  4. Delete the Amazon Redshift workgroup.
  5. Clean up resources in your Google account by deleting the project that contains the Google BigQuery resources. Follow the documentation to clean up the Google resources.

Conclusion

In this post, we walked you through the process of using Amazon AppFlow to integrate data from Google Ads and Google Sheets. We demonstrated how the complexities of data integration are minimized so you can focus on deriving actionable insights from your data. Whether you’re archiving historical data, performing complex analytics, or preparing data for machine learning, this connector streamlines the process, making it accessible to a broader range of data professionals.

For more information, refer to Amazon AppFlow support for Google Sheets and Google Ads.


About the authors

Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.

Tahir Aziz is an Analytics Solution Architect at AWS. He has worked with building data warehouses and big data solutions for over 13 years. He loves to help customers design end-to-end analytics solutions on AWS. Outside of work, he enjoys traveling and cooking.

Raza Hafeez is a Senior Product Manager at Amazon Redshift. He has over 13 years of professional experience building and optimizing enterprise data warehouses and is passionate about enabling customers to realize the power of their data. He specializes in migrating enterprise data warehouses to AWS Modern Data Architecture.

Amit Ghodke is an Analytics Specialist Solutions Architect based out of Austin. He has worked with databases, data warehouses and analytical applications for the past 16 years. He loves to help customers implement analytical solutions at scale to derive maximum business value.

Amazon EMR 7.5 runtime for Apache Spark and Iceberg can run Spark workloads 3.6 times faster than Spark 3.5.3 and Iceberg 1.6.1

Post Syndicated from Atul Payapilly original https://aws.amazon.com/blogs/big-data/amazon-emr-7-5-runtime-for-apache-spark-and-iceberg-can-run-spark-workloads-3-6-times-faster-than-spark-3-5-3-and-iceberg-1-6-1/

The Amazon EMR runtime for Apache Spark offers a high-performance runtime environment while maintaining 100% API compatibility with open source Apache Spark and Apache Iceberg table format. Amazon EMR on EC2, Amazon EMR Serverless, Amazon EMR on Amazon EKS, Amazon EMR on AWS Outposts and AWS Glue all use the optimized runtimes.

In this post, we demonstrate the performance benefits of using the Amazon EMR 7.5 runtime for Spark and Iceberg compared to open source Spark 3.5.3 with Iceberg 1.6.1 tables on the TPC-DS 3TB benchmark v2.13.

Iceberg is a popular open source high-performance format for large analytic tables. Our benchmarks demonstrate that Amazon EMR can run TPC-DS 3 TB workloads 3.6 times faster, reducing the runtime from 1.54 hours to 0.42 hours. Additionally, the cost efficiency improves by 2.9 times, with the total cost decreasing from $16.00 to $5.39 when using Amazon Elastic Compute Cloud (Amazon EC2) On-Demand r5d.4xlarge instances, providing observable gains for data processing tasks.

This is a further 32% increase from the optimizations shipped in Amazon EMR 7.1 covered in a previous post, Amazon EMR 7.1 runtime for Apache Spark and Iceberg can run Spark workloads 2.7 times faster than Apache Spark 3.5.1 and Iceberg 1.5.2. Since then we have continued adding more support for DataSource V2 for eight more existing query optimizations in the EMR runtime for Spark.

In addition to these DataSource V2 specific improvements, we have made more optimizations to Spark operators since Amazon EMR 7.1 that also contribute to the additional speedup.

Benchmark results for Amazon EMR 7.5 compared to4 open source Spark 3.5.3 and Iceberg 1.6.1

To assess the Spark engine’s performance with the Iceberg table format, we performed benchmark tests using the 3 TB TPC-DS dataset, version 2.13 (our results derived from the TPC-DS dataset are not directly comparable to the official TPC-DS results due to setup differences). Benchmark tests for the EMR runtime for Spark and Iceberg were conducted on Amazon EMR 7.5 EC2 clusters vs open source Spark 3.5.3 and Iceberg 1.6.1 on EC2 clusters.

The setup instructions and technical details are available in our GitHub repository. To minimize the influence of external catalogs like AWS Glue and Hive, we used the Hadoop catalog for the Iceberg tables. This uses the underlying file system, specifically Amazon S3, as the catalog. We can define this setup by configuring the property spark.sql.catalog.<catalog_name>.type. The fact tables used the default partitioning by the date column, which have a number of partitions varying from 200–2,100. No precalculated statistics were used for these tables.

We ran a total of 104 SparkSQL queries in three sequential rounds, and the average runtime of each query across these rounds was taken for comparison. The average runtime for the three rounds on Amazon EMR 7.5 with Iceberg enabled was 0.42 hours, demonstrating a 3.6-fold speed increase compared to open source Spark 3.5.3 and Iceberg 1.6.1. The following figure presents the total runtimes in seconds.

EMR vs OSS runtime

The following table summarizes the metrics.

Metric Amazon EMR 7.5 on EC2 Amazon EMR 7.1 on EC2 Open Source Spark 3.5.3 and Iceberg 1.6.1
Average runtime in seconds 1535.62 2033.17 5546.16
Geometric mean over queries in seconds 8.30046 10.13153 20.40555
Cost* $5.39 $7.18 $16.00

*Detailed cost estimates are discussed later in this post.

The following chart demonstrates the per-query performance improvement of Amazon EMR 7.5 relative to open source Spark 3.5.3 and Iceberg 1.6.1. The extent of the speedup varies from one query to another, with the fastest up to 9.4 times faster for q93, with Amazon EMR outperforming open source Spark with Iceberg tables. The horizontal axis arranges the TPC-DS 3TB benchmark queries in descending order based on the performance improvement seen with Amazon EMR, and the vertical axis depicts the magnitude of this speedup as a ratio.

EMR vs OSS per query cost

Cost comparison

Our benchmark provides the total runtime and geometric mean data to assess the performance of Spark and Iceberg in a complex, real-world decision support scenario. For additional insights, we also examine the cost aspect. We calculate cost estimates using formulas that account for EC2 On-Demand instances, Amazon Elastic Block Store (Amazon EBS), and Amazon EMR expenses.

  • Amazon EC2 cost (includes SSD cost) = number of instances * r5d.4xlarge hourly rate * job runtime in hours
    • r5d.4xlarge hourly rate = $1.152 per hour in us-east-1
  • Root Amazon EBS cost = number of instances * Amazon EBS per GB-hourly rate * root EBS volume size * job runtime in hours
  • Amazon EMR cost = number of instances * r5d.4xlarge Amazon EMR cost * job runtime in hours
    • 4xlarge Amazon EMR cost = $0.27 per hour
  • Total cost = Amazon EC2 cost + root Amazon EBS cost + Amazon EMR cost

The calculations reveal that the Amazon EMR 7.5 benchmark yields a 2.9-fold cost efficiency improvement over open source Spark 3.5.3 and Iceberg 1.6.1 in running the benchmark job.

Metric Amazon EMR 7.5 Amazon EMR 7.1 Open Source Spark 3.5.1 and Iceberg 1.5.2
Runtime in hours 0.426 0.564 1.540

Number of EC2 instances

(Includes primary node)

9 9 9
Amazon EBS Size 20gb 20gb 20gb

Amazon EC2

(Total runtime cost)

$4.35 $5.81 $15.97
Amazon EBS cost $0.01 $0.01 $0.04
Amazon EMR cost $1.02 $1.36 $0
Total cost $5.38 $7.18 $16.01
Cost savings Amazon EMR 7.5 is 2.9 times better Amazon EMR 7.1 is 2.2 times better Baseline

In addition to the time-based metrics discussed so far, data from Spark event logs show that Amazon EMR scanned approximately 3.4 times less data from Amazon S3 and 4.1 times fewer records than the open source version in the TPC-DS 3 TB benchmark. This reduction in Amazon S3 data scanning contributes directly to cost savings for Amazon EMR workloads.

Run open source Spark benchmarks on Iceberg tables

We used separate EC2 clusters, each equipped with nine r5d.4xlarge instances, for testing both open source Spark 3.5.3 and Amazon EMR 7.5 for Iceberg workload. The primary node was equipped with 16 vCPU and 128 GB of memory, and the eight worker nodes together had 128 vCPU and 1024 GB of memory. We conducted tests using the Amazon EMR default settings to showcase the typical user experience and minimally adjusted the settings of Spark and Iceberg to maintain a balanced comparison.

The following table summarizes the Amazon EC2 configurations for the primary node and eight worker nodes of type r5d.4xlarge.

EC2 Instance vCPU Memory (GiB) Instance Storage (GB) EBS Root Volume (GB)
r5d.4xlarge 16 128 2 x 300 NVMe SSD 20 GB

Prerequisites

The following prerequisites are required to run the benchmarking:

  1. Using the instructions in the emr-spark-benchmark GitHub repo, set up the TPC-DS source data in your S3 bucket and on your local computer.
  2. Build the benchmark application following the steps provided in Steps to build spark-benchmark-assembly application and copy the benchmark application to your S3 bucket. Alternatively, copy spark-benchmark-assembly-3.5.3.jar to your S3 bucket.
  3. Create Iceberg tables from the TPC-DS source data. Follow the instructions on GitHub to create Iceberg tables using the Hadoop catalog. For example, the following code uses an EMR 7.5 cluster with Iceberg enabled to create the tables:
aws emr add-steps 
--cluster-id <cluster-id> --steps Type=Spark,Name="Create Iceberg Tables",
Args=[--class,com.amazonaws.eks.tpcds.CreateIcebergTables,--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.hadoop_catalog=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.hadoop_catalog.type=hadoop,
--conf,spark.sql.catalog.hadoop_catalog.warehouse=s3://<bucket>/<warehouse_path>/,
--conf,spark.sql.catalog.hadoop_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<bucket>/<jar_location>/spark-benchmark-assembly-3.5.3.jar,s3://blogpost-sparkoneks-us-east-1/blog/BLOG_TPCDS-TEST-3T-partitioned/,
/home/hadoop/tpcds-kit/tools,parquet,3000,true,<database_name>,true,true],ActionOnFailure=CONTINUE --region <AWS region>

Note the Hadoop catalog warehouse location and database name from the preceding step. We use the same iceberg tables to run benchmarks with Amazon EMR 7.5 and open source Spark.

This benchmark application is built from the branch tpcds-v2.13_iceberg. If you’re building a new benchmark application, switch to the correct branch after downloading the source code from the GitHub repo.

Create and configure a YARN cluster on Amazon EC2

To compare Iceberg performance between Amazon EMR on Amazon EC2 and open source Spark on Amazon EC2, follow the instructions in the emr-spark-benchmark GitHub repo to create an open source Spark cluster on Amazon EC2 using Flintrock with eight worker nodes.

Based on the cluster selection for this test, the following configurations are used:

Make sure to replace the placeholder <private ip of primary node>, in the yarn-site.xml file, with the primary node’s IP address of your Flintrock cluster.

Run the TPC-DS benchmark with Spark 3.5.3 and Iceberg 1.6.1

Complete the following steps to run the TPC-DS benchmark:

  1. Log in to the open source cluster primary node using flintrock login $CLUSTER_NAME.
  2. Submit your Spark job:
    1. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables.
    2. The results are created in s3://<YOUR_S3_BUCKET>/benchmark_run.
    3. You can track progress in /media/ephemeral0/spark_run.log.
spark-submit \
--master yarn \
--deploy-mode client \
--class com.amazonaws.eks.tpcds.BenchmarkSQL \
--conf spark.driver.cores=4 \
--conf spark.driver.memory=10g \
--conf spark.executor.cores=16 \
--conf spark.executor.memory=100g \
--conf spark.executor.instances=8 \
--conf spark.network.timeout=2000 \
--conf spark.executor.heartbeatInterval=300s \
--conf spark.dynamicAllocation.enabled=false \
--conf spark.shuffle.service.enabled=false \
--conf spark.hadoop.fs.s3a.aws.credentials.provider=com.amazonaws.auth.InstanceProfileCredentialsProvider \
--conf spark.hadoop.fs.s3.impl=org.apache.hadoop.fs.s3a.S3AFileSystem \
--conf spark.jars.packages=org.apache.hadoop:hadoop-aws:3.3.4,org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.6.1,org.apache.iceberg:iceberg-aws-bundle:1.6.1 \
--conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions   \
--conf spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog    \
--conf spark.sql.catalog.local.type=hadoop  \
--conf spark.sql.catalog.local.warehouse=s3a://<YOUR_S3_BUCKET>/<warehouse_path>/ \
--conf spark.sql.defaultCatalog=local   \
--conf spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO   \
spark-benchmark-assembly-3.5.3.jar   \
s3://<YOUR_S3_BUCKET>/benchmark_run 3000 1 false  \
q1-v2.13,q10-v2.13,q11-v2.13,q12-v2.13,q13-v2.13,q14a-v2.13,q14b-v2.13,q15-v2.13,q16-v2.13,\
q17-v2.13,q18-v2.13,q19-v2.13,q2-v2.13,q20-v2.13,q21-v2.13,q22-v2.13,q23a-v2.13,q23b-v2.13,\
q24a-v2.13,q24b-v2.13,q25-v2.13,q26-v2.13,q27-v2.13,q28-v2.13,q29-v2.13,q3-v2.13,q30-v2.13,\
q31-v2.13,q32-v2.13,q33-v2.13,q34-v2.13,q35-v2.13,q36-v2.13,q37-v2.13,q38-v2.13,q39a-v2.13,\
q39b-v2.13,q4-v2.13,q40-v2.13,q41-v2.13,q42-v2.13,q43-v2.13,q44-v2.13,q45-v2.13,q46-v2.13,\
q47-v2.13,q48-v2.13,q49-v2.13,q5-v2.13,q50-v2.13,q51-v2.13,q52-v2.13,q53-v2.13,q54-v2.13,\
q55-v2.13,q56-v2.13,q57-v2.13,q58-v2.13,q59-v2.13,q6-v2.13,q60-v2.13,q61-v2.13,q62-v2.13,\
q63-v2.13,q64-v2.13,q65-v2.13,q66-v2.13,q67-v2.13,q68-v2.13,q69-v2.13,q7-v2.13,q70-v2.13,\
q71-v2.13,q72-v2.13,q73-v2.13,q74-v2.13,q75-v2.13,q76-v2.13,q77-v2.13,q78-v2.13,q79-v2.13,\
q8-v2.13,q80-v2.13,q81-v2.13,q82-v2.13,q83-v2.13,q84-v2.13,q85-v2.13,q86-v2.13,q87-v2.13,\
q88-v2.13,q89-v2.13,q9-v2.13,q90-v2.13,q91-v2.13,q92-v2.13,q93-v2.13,q94-v2.13,q95-v2.13,\
q96-v2.13,q97-v2.13,q98-v2.13,q99-v2.13,ss_max-v2.13    \
true <database> > /media/ephemeral0/spark_run.log 2>&1 &!

Summarize the results

After the Spark job finishes, retrieve the test result file from the output S3 bucket at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv. This can be done either through the Amazon S3 console by navigating to the specified bucket location or by using the AWS Command Line Interface (AWS CLI). The Spark benchmark application organizes the data by creating a timestamp folder and placing a summary file within a folder labeled summary.csv. The output CSV files contain four columns without headers:

  • Query name
  • Median time
  • Minimum time
  • Maximum time

With the data from three separate test runs with one iteration each time, we can calculate the average and geometric mean of the benchmark runtimes.

Run the TPC-DS benchmark with the EMR runtime for Spark

Most of the instructions are similar to Steps to run Spark Benchmarking with a few Iceberg-specific details.

Prerequisites

Complete the following prerequisite steps:

  1. Run aws configure to configure the AWS CLI shell to point to the benchmarking AWS account. Refer to Configure the AWS CLI for instructions.
  2. Upload the benchmark application JAR file to Amazon S3.

Deploy the EMR cluster and run the benchmark job

Complete the following steps to run the benchmark job:

  1. Use the AWS CLI command as shown in Deploy EMR on EC2 Cluster and run benchmark job to spin up an EMR on EC2 cluster. Make sure to enable Iceberg. See Create an Iceberg cluster for more details. Choose the correct Amazon EMR version, root volume size, and same resource configuration as the open source Flintrock setup. Refer to create-cluster for a detailed description of the AWS CLI options.
  2. Store the cluster ID from the response. We need this for the next step.
  3. Submit the benchmark job in Amazon EMR using add-steps from the AWS CLI:
    1. Replace <cluster ID> with the cluster ID from Step 2.
    2. The benchmark application is at s3://<your-bucket>/spark-benchmark-assembly-3.5.3.jar.
    3. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables. This should be the same as the one used for the open source TPC-DS benchmark run.
    4. The results will be in s3://<your-bucket>/benchmark_run.
aws emr add-steps   --cluster-id <cluster-id>
--steps Type=Spark,Name="SPARK Iceberg EMR TPCDS Benchmark Job",
Args=[--class,com.amazonaws.eks.tpcds.BenchmarkSQL,
--conf,spark.driver.cores=4,
--conf,spark.driver.memory=10g,
--conf,spark.executor.cores=16,
--conf,spark.executor.memory=100g,
--conf,spark.executor.instances=8,
--conf,spark.network.timeout=2000,
--conf,spark.executor.heartbeatInterval=300s,
--conf,spark.dynamicAllocation.enabled=false,
--conf,spark.shuffle.service.enabled=false,
--conf,spark.sql.iceberg.data-prefetch.enabled=true,
--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.local.type=hadoop,
--conf,spark.sql.catalog.local.warehouse=s3://<your-bucket>/<warehouse-path>,
--conf,spark.sql.defaultCatalog=local,
--conf,spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<your-bucket>/spark-benchmark-assembly-3.5.3.jar,
s3://<your-bucket>/benchmark_run,3000,1,false,
'q1-v2.13\,q10-v2.13\,q11-v2.13\,q12-v2.13\,q13-v2.13\,q14a-v2.13\,q14b-v2.13\,q15-v2.13\,q16-v2.13\,q17-v2.13\,q18-v2.13\,q19-v2.13\,q2-v2.13\,q20-v2.13\,q21-v2.13\,q22-v2.13\,q23a-v2.13\,q23b-v2.13\,q24a-v2.13\,q24b-v2.13\,q25-v2.13\,q26-v2.13\,q27-v2.13\,q28-v2.13\,q29-v2.13\,q3-v2.13\,q30-v2.13\,q31-v2.13\,q32-v2.13\,q33-v2.13\,q34-v2.13\,q35-v2.13\,q36-v2.13\,q37-v2.13\,q38-v2.13\,q39a-v2.13\,q39b-v2.13\,q4-v2.13\,q40-v2.13\,q41-v2.13\,q42-v2.13\,q43-v2.13\,q44-v2.13\,q45-v2.13\,q46-v2.13\,q47-v2.13\,q48-v2.13\,q49-v2.13\,q5-v2.13\,q50-v2.13\,q51-v2.13\,q52-v2.13\,q53-v2.13\,q54-v2.13\,q55-v2.13\,q56-v2.13\,q57-v2.13\,q58-v2.13\,q59-v2.13\,q6-v2.13\,q60-v2.13\,q61-v2.13\,q62-v2.13\,q63-v2.13\,q64-v2.13\,q65-v2.13\,q66-v2.13\,q67-v2.13\,q68-v2.13\,q69-v2.13\,q7-v2.13\,q70-v2.13\,q71-v2.13\,q72-v2.13\,q73-v2.13\,q74-v2.13\,q75-v2.13\,q76-v2.13\,q77-v2.13\,q78-v2.13\,q79-v2.13\,q8-v2.13\,q80-v2.13\,q81-v2.13\,q82-v2.13\,q83-v2.13\,q84-v2.13\,q85-v2.13\,q86-v2.13\,q87-v2.13\,q88-v2.13\,q89-v2.13\,q9-v2.13\,q90-v2.13\,q91-v2.13\,q92-v2.13\,q93-v2.13\,q94-v2.13\,q95-v2.13\,q96-v2.13\,q97-v2.13\,q98-v2.13\,q99-v2.13\,ss_max-v2.13',
true,<database>],ActionOnFailure=CONTINUE --region <aws-region>

Summarize the results

After the step is complete, you can see the summarized benchmark result at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv in the same way as the previous run and compute the average and geometric mean of the query runtimes.

Clean up

To prevent any future charges, delete the resources you created by following the instructions provided in the Cleanup section of the GitHub repository.

Summary

Amazon EMR is consistently enhancing the EMR runtime for Spark when used with Iceberg tables, achieving a performance that is 3.6 times faster than open source Spark 3.5.3 and Iceberg 1.6.1 with EMR 7.5 on TPC-DS 3 TB, v2.13. This is a further increase of 32% from EMR 7.1. We encourage you to keep up to date with the latest Amazon EMR releases to fully benefit from ongoing performance improvements.

To stay informed, subscribe to the AWS Big Data Blog’s RSS feed, where you can find updates on the EMR runtime for Spark and Iceberg, as well as tips on configuration best practices and tuning recommendations.


About the Authors

Atul Felix Payapilly is a software development engineer for Amazon EMR at Amazon Web Services.

Udit Mehrotra is an Engineering Manager for EMR at Amazon Web Services.

Accelerate queries on Apache Iceberg tables through AWS Glue auto compaction

Post Syndicated from Navnit Shukla original https://aws.amazon.com/blogs/big-data/accelerate-queries-on-apache-iceberg-tables-through-aws-glue-auto-compaction/

Data lakes were originally designed to store large volumes of raw, unstructured, or semi-structured data at a low cost, primarily serving big data and analytics use cases. Over time, as organizations began to explore broader applications, data lakes have become essential for various data-driven processes beyond just reporting and analytics. Today, they play a critical role in syncing with customer applications, enabling the ability to manage concurrent data operations while maintaining the integrity and consistency of information. This shift includes not only storing batch data but also ingesting and processing near real-time data streams, allowing businesses to merge historical insights with live data to power more responsive and adaptive decision-making. However, this new data lake architecture brings challenges around managing transactional support and handling the influx of small files generated by real-time data streams. Traditionally, customers addressed these challenges by performing complex extract, transform, and load (ETL) processes, which often led to data duplication and increased complexity in data pipelines. Additionally, to cope with the proliferation of small files, organizations had to develop custom mechanisms to compact and merge these files, leading to the creation and maintenance of bespoke solutions that were difficult to scale and manage. As data lakes increasingly handle sensitive business data and transactional workloads, maintaining strong data quality, governance, and compliance becomes vital to maintaining trust and regulatory alignment.

To simplify these challenges, organizations have adopted open table formats (OTFs) like Apache Iceberg, which provide built-in transactional capabilities and mechanisms for compaction. OTFs, such as Iceberg, address key limitations in traditional data lakes by offering features like ACID transactions, which maintain data consistency across concurrent operations, and compaction, which helps manage the issue of small files by merging them efficiently. By using features like Iceberg’s compaction, OTFs streamline maintenance, making it straightforward to manage object and metadata versioning at scale. However, although OTFs reduce the complexity of maintaining efficient tables, they still require some regular maintenance to make sure tables remain in an optimal state.

In this post, we explore new features of the AWS Glue Data Catalog, which now supports improved automatic compaction of Iceberg tables for streaming data, making it straightforward for you to keep your transactional data lakes consistently performant. Enabling automatic compaction on Iceberg tables reduces metadata overhead on your Iceberg tables and improves query performance. Many customers have streaming data continuously ingested in Iceberg tables, resulting in a large number of delete files that track changes in data files. With this new feature, as you enable the Data Catalog optimizer. It constantly monitors table partitions and runs the compaction process for both data and delta or delete files, and it regularly commits partial progress. The Data Catalog also now supports heavily nested complex data and supports schema evolution as you reorder or rename columns.

Automatic compaction with AWS Glue

Automatic compaction in the Data Catalog makes sure your Iceberg tables are always in optimal condition. The data compaction optimizer continuously monitors table partitions and invokes the compaction process when specific thresholds for the number of files and file sizes are met. For example, based on the Iceberg table configuration of the target file size, the compaction process will start and continue if the table or any of the partitions within the table have more than the default configuration (for example 100 files), each smaller than 75% of the target file size.

Iceberg supports two table modes: Merge-on-Read (MoR) and Copy-on-Write (CoW). These table modes provide different approaches for handling data updates and play a critical role in how data lakes manage changes and maintain performance:

  • Data compaction on Iceberg CoW – With CoW, any updates or deletes are directly applied to the table files. This means the entire dataset is rewritten when changes are made. Although this provides immediate consistency and simplifies reads (because readers only access the latest snapshot of the data), it can become costly and slow for write-heavy workloads due to the need for frequent rewrites. Announced during AWS re:Invent 2023, this feature focuses on optimizing data storage for Iceberg tables using the CoW mechanism. Compaction in CoW makes sure updates to the data result in new files being created, which are then compacted to improve query performance.
  • Data compaction on Iceberg MoR – Unlike CoW, MoR allows updates to be written separately from the existing dataset, and those changes are only merged when the data is read. This approach is beneficial for write-heavy scenarios because it avoids frequent full table rewrites. However, it can introduce complexity during reads because the system has to merge base and delta files as needed to provide a complete view of the data. MoR compaction, now generally available, allows for efficient handling of streaming data. It makes sure that while data is being continuously ingested, it’s also compacted in a way that optimizes read performance without compromising the ingestion speed.

Whether you are using CoW, MoR, or a hybrid of both, one challenge remains consistent: maintenance around the growing number of small files generated by each transaction. AWS Glue automatic compaction addresses this by making sure your Iceberg tables remain efficient and performant across both table modes.

This post provides a detailed comparison of query performance between auto compacted and non-compacted Iceberg tables. By analyzing key metrics such as query latency and storage efficiency, we demonstrate how the automatic compaction feature optimizes data lakes for better performance and cost savings. This comparison will help guide you in making informed decisions on enhancing your data lake environments.

Solution overview

This blog post explores the performance benefits of the newly launched feature in AWS Glue that supports automatic compaction of Iceberg tables with MoR capabilities. We run two versions of the same architecture: one where the tables are auto compacted, and another without compaction. By comparing both scenarios, this post demonstrates the efficiency, query performance, and cost benefits of auto compacted tables vs. non-compacted tables in a simulated Internet of Things (IoT) data pipeline.

The following diagram illustrates the solution architecture.

The solution consists of the following components:

  • Amazon Elastic Compute Cloud (Amazon EC2) simulates continuous IoT data streams, sending them to Amazon MSK for processing
  • Amazon Managed Streaming for Apache Kafka (Amazon MSK) ingests and streams data from the IoT simulator for real-time processing
  • Amazon EMR Serverless processes streaming data from Amazon MSK without managing clusters, writing results to the Amazon S3 data lake
  • Amazon Simple Storage Service (Amazon S3) stores data using Iceberg’s MoR format for efficient querying and analysis
  • The Data Catalog manages metadata for the datasets in Amazon S3, enabling organized data discovery and querying through Amazon Athena
  • Amazon Athena queries data from the S3 data lake with two table options:
    • Non-compacted table – Queries raw data from the Iceberg table
    • Compacted table – Queries data optimized by automatic compaction for faster performance.

The data flow consists of the following steps:

  1. The IoT simulator on Amazon EC2 generates continuous data streams.
  2. The data is sent to Amazon MSK, which acts as a streaming table.
  3. EMR Serverless processes streaming data and writes the output to Amazon S3 in Iceberg format.
  4. The Data Catalog manages the metadata for the datasets.
  5. Athena is used to query the data, either directly from the non-compacted table or from the compacted table after auto compaction.

In this post, we guide you through setting up an evaluation environment for AWS Glue Iceberg auto compaction performance using the following GitHub repository. The process involves simulating IoT data ingestion, deduplication, and querying performance using Athena.

Compaction IoT performance test

We simulated IoT data ingestion with over 20 billion events and used MERGE INTO for data deduplication across two time-based partitions, involving heavy partition reads and shuffling. After ingestion, we ran queries in Athena to compare performance between compacted and non-compacted tables using the MoR format. This test aims to have low latency on ingestion but will lead to hundreds of millions of small files.

We use the following table configuration settings:

'write.delete.mode'='merge-on-read'
'write.update.mode'='merge-on-read'
'write.merge.mode'='merge-on-read'
'write.distribution.mode=none'

We use 'write.distribution.mode=none' to lower the latency. However, it will increase the number of Parquet files. For other scenarios, you may want to use hash or range distribution write modes to reduce the file count.

This test makes make append operations because we’re appending new data to the table but we don’t have any delete operations.

The following table shows some metrics of the Athena query performance.


Execution Time (sec) Performance Improvement (%) Data Scanned (GB)
Query employee (without compaction) employeeauto (with compaction) employee (without compaction) employeeauto (with compaction)
SELECT count(*) FROM "bigdata"."<tablename>" 67.5896 3.8472 94.31% 0 0
SELECT team, name, min(age) AS youngest_age
FROM "bigdata"."<tablename>"
GROUP BY team, name
ORDER BY youngest_age ASC
72.0152 50.4308 29.97% 33.72 32.96
SELECT role, team, avg(age) AS average_age
FROM bigdata."<tablename>"
GROUP BY role, team
ORDER BY average_age DESC
74.1430 37.7676 49.06% 17.24 16.59
SELECT name, age, start_date, role, team
FROM bigdata."<tablename>"
WHERE
CAST(start_date as DATE) > CAST('2023-01-02' as DATE) and
age > 40
ORDER BY start_date DESC
limit 100
70.3376 37.1232 47.22% 105.74 110.32

Because the previous test didn’t perform any delete operations on the table, we conduct a new test involving hundreds of thousands of such operations. We use the previously auto compacted table (employeeauto) as a base, noting that this table uses MoR for all operations.

We run a query that deletes data from each even second on the table:

DELETE FROM iceberg_catalog.bigdata.employeeauto
WHERE start_date BETWEEN 'start' AND 'end'
AND SECOND(start_date) % 2 = 0;

This query runs with table optimizations enabled, using an Amazon EMR Studio notebook. After running the queries, we roll back the table to its previous state for a performance comparison. Iceberg’s time-traveling capabilities allow us to restore the table. We then disable the table optimizations, rerun the delete query, and follow up with Athena queries to analyze performance differences. The following table summarizes our results.


Execution Time (sec) Performance Improvement (%) Data Scanned (GB)
Query employee (without compaction) employeeauto (with compaction) employee (without compaction) employeeauto (with compaction)
SELECT count(*) FROM "bigdata"."<tablename>" 29.820 8.71 70.77% 0 0
SELECT team, name, min(age) as youngest_age
FROM "bigdata"."<tablename>"
GROUP BY team, name
ORDER BY youngest_age ASC
58.0600 34.1320 41.21% 33.27 19.13
SELECT role, team, avg(age) AS average_age
FROM bigdata."<tablename>"
GROUP BY role, team
ORDER BY average_age DESC
59.2100 31.8492 46.21% 16.75 9.73
SELECT name, age, start_date, role, team
FROM bigdata."<tablename>"
WHERE
CAST(start_date as DATE) > CAST('2023-01-02' as DATE) and
age > 40
ORDER BY start_date DESC
limit 100
68.4650 33.1720 51.55% 112.64 61.18

We analyze the following key metrics:

  • Query runtime – We compared the runtimes between compacted and non-compacted tables using Athena as the query engine and found significant performance improvements with both MoR for ingestion and appends and MoR for delete operations.
  • Data scanned evaluation – We compared compacted and non-compacted tables using Athena as the query engine and observed a reduction in data scanned for most queries. This reduction translates directly into cost savings.

Prerequisites

To set up your own evaluation environment and test the feature, you need the following prerequisites:

  • A virtual private cloud (VPC) with at least two private subnets. For instructions, see Create a VPC.
  • An EC2 instance c5.xlarge using Amazon Linux 2023 running on one of those private subnets where you will launch the data simulator. For the security group, you can use the default for the VPC. For more information, see Get started with Amazon EC2.
  • An AWS Identity and Access Management (IAM) user with the correct permissions to create and configure all the required resources.

Set up Amazon S3 storage

Create an S3 bucket with the following structure:

s3bucket/
/jars
/employee.desc
/warehouse
/checkpoint
/checkpointAuto

Download the descriptor file employee.desc from the GitHub repo and place it in the S3 bucket.

Download the application on the releases page

Get the packaged application from the GitHub repo, then upload the JAR file to the jars directory on the S3 bucket. The warehouse will be where the Iceberg data and metadata will live and checkpoint will be used for the Structured Streaming checkpointing mechanism. Because we use two streaming job runs, one for compacted and one for non-compacted data, we also create a checkpointAuto folder.

Create a Data Catalog database

Create a database in the Data Catalog (for this post, we name our database bigdata). For instructions, see Getting started with the AWS Glue Data Catalog.

Create an EMR Serverless application

Create an EMR Serverless application with the following settings (for instructions, see Getting started with Amazon EMR Serverless):

  • Type: Spark
  • Version: 7.1.0
  • Architecture: x86_64
  • Java Runtime: Java 17
  • Metastore Integration: AWS Glue Data Catalog
  • Logs: Enable Amazon CloudWatch Logs if desired

Configure the network (VPC, subnets, and default security group) to allow the EMR Serverless application to reach the MSK cluster.

Take note of the application-id to use later for launching the jobs.

Create an MSK cluster

Create an MSK cluster on the Amazon MSK console. For more details, see Get started using Amazon MSK.

You need to use custom create with at least two brokers using 3.5.1, Apache Zookeeper mode version, and instance type kafka.m7g.xlarge. Do not use public access; choose two private subnets to deploy it (one broker per subnet or Availability Zone, for a total of two brokers). For the security group, remember that the EMR cluster and the Amazon EC2 based producer will need to reach the cluster and act accordingly. For security, use PLAINTEXT (in production, you should secure access to the cluster). Choose 200 GB as storage size for each broker and do not enable tiered storage. For network security groups, you can choose the default of the VPC.

For the MSK cluster configuration, use the following settings:

auto.create.topics.enable=true
default.replication.factor=2
min.insync.replicas=2
num.io.threads=8
num.network.threads=5
num.partitions=32
num.replica.fetchers=2
replica.lag.time.max.ms=30000
socket.receive.buffer.bytes=102400
socket.request.max.bytes=104857600
socket.send.buffer.bytes=102400
unclean.leader.election.enable=true
zookeeper.session.timeout.ms=18000
compression.type=zstd
log.retention.hours=2
log.retention.bytes=10073741824

Configure the data simulator

Log in to your EC2 instance. Because it’s running on a private subnet, you can use an instance endpoint to connect. To create one, see Connect to your instances using EC2 Instance Connect Endpoint. After you log in, issue the following commands:

sudo yum install java-17-amazon-corretto-devel
wget https://archive.apache.org/dist/kafka/3.5.1/kafka_2.12-3.5.1.tgz
tar xzvf kafka_2.12-3.5.1.tgz

Create Kafka topics

Create two Kafka topics—remember that you need to change the bootstrap server with the corresponding client information. You can get this data from the Amazon MSK console on the details page for your MSK cluster.

cd kafka_2.12-3.5.1/bin/

./kafka-topics.sh --topic protobuf-demo-topic-pure-auto --bootstrap-server kafkaBoostrapString --create
./kafka-topics.sh --topic protobuf-demo-topic-pure --bootstrap-server kafkaBoostrapString –create

Launch job runs

Issue job runs for the non-compacted and auto compacted tables using the following AWS Command Line Interface (AWS CLI) commands. You can use AWS CloudShell to run the commands.

For the non-compacted table, you need to change the s3bucket value as needed and the application-id. You also need an IAM role (execution-role-arn) with the corresponding permissions to access the S3 bucket and to access and write tables on the Data Catalog.

aws emr-serverless start-job-run --application-id application-identifier --name job-run-name --execution-role-arn arn-of-emrserverless-role --mode 'STREAMING' --job-driver '{
"sparkSubmit": {
"entryPoint": "s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar",
"entryPointArguments": ["true","s3://s3bucket/warehouse","s3://s3bucket/Employee.desc","s3://s3bucket/checkpoint","kafkaBootstrapString","true"],
"sparkSubmitParameters": "--class com.aws.emr.spark.iot.SparkCustomIcebergIngestMoR --conf spark.executor.cores=16 --conf spark.executor.memory=64g --conf spark.driver.cores=4 --conf spark.driver.memory=16g --conf spark.dynamicAllocation.minExecutors=3 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.dynamicAllocation.maxExecutors=5 --conf spark.sql.catalog.glue_catalog.http-client.apache.max-connections=3000 --conf spark.emr-serverless.executor.disk.type=shuffle_optimized --conf spark.emr-serverless.executor.disk=1000G --files s3://s3bucket/Employee.desc --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1"
}
}'

For the auto compacted table, you need to change the s3bucket value as needed, the application-id, and the kafkaBootstrapString. You also need an IAM role (execution-role-arn) with the corresponding permissions to access the S3 bucket and to access and write tables on the Data Catalog.

aws emr-serverless start-job-run --application-id application-identifier --name job-run-name --execution-role-arn arn-of-emrserverless-role --mode 'STREAMING' --job-driver '{
"sparkSubmit": {
"entryPoint": "s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar",
"entryPointArguments": ["true","s3://s3bucket/warehouse","/home/hadoop/Employee.desc","s3://s3bucket/checkpointAuto","kafkaBootstrapString","true"],
"sparkSubmitParameters": "--class com.aws.emr.spark.iot.SparkCustomIcebergIngestMoRAuto --conf spark.executor.cores=16 --conf spark.executor.memory=64g --conf spark.driver.cores=4 --conf spark.driver.memory=16g --conf spark.dynamicAllocation.minExecutors=3 --conf spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar --conf spark.dynamicAllocation.maxExecutors=5 --conf spark.sql.catalog.glue_catalog.http-client.apache.max-connections=3000 --conf spark.emr-serverless.executor.disk.type=shuffle_optimized --conf spark.emr-serverless.executor.disk=1000G --files s3://s3bucket/Employee.desc --packages org.apache.spark:spark-sql-kafka-0-10_2.12:3.5.1"
}
}'

Enable auto compaction

Enable auto compaction for the employeeauto table in AWS Glue. For instructions, see Enabling compaction optimizer.

Launch the data simulator

Download the JAR file to the EC2 instance and run the producer:

aws s3 cp s3://s3bucket/jars/streaming-iceberg-ingest-1.0-SNAPSHOT.jar .

Now you can start the protocol buffer producers.

For non-compacted tables, use the following commands:

java -cp streaming-iceberg-ingest-1.0-SNAPSHOT.jar 
com.aws.emr.proto.kafka.producer.ProtoProducer kafkaBoostrapString

For auto compacted tables, use the following commands:

java -cp streaming-iceberg-ingest-1.0-SNAPSHOT.jar 
com.aws.emr.proto.kafka.producer.ProtoProducerAuto kafkaBoostrapString

Test the solution in EMR Studio

For the delete test, we use an EMR Studio. For setup instructions, see Set up an EMR Studio. Next, you need to create an EMR Serverless interactive application to run the notebook; refer to Run interactive workloads with EMR Serverless through EMR Studio to create a Workspace.

Open the Workspace, select the interactive EMR Serverless application as the compute option, and attach it.

Download the Jupyter notebook, upload it to your environment, and run the cells using a PySpark kernel to run the test.

Clean up

This evaluation is for high-throughput scenarios and can lead to significant costs. Complete the following steps to clean up your resources:

  1. Stop the Kafka producer EC2 instance.
  2. Cancel the EMR job runs and delete the EMR Serverless application.
  3. Delete the MSK cluster.
  4. Delete the tables and database from the Data Catalog.
  5. Delete the S3 bucket.

Conclusion

The Data Catalog has improved automatic compaction of Iceberg tables for streaming data, making it straightforward for you to keep your transactional data lakes always performant. Enabling automatic compaction on Iceberg tables reduces metadata overhead on your Iceberg tables and improves query performance.

Many customers have streaming data that is continuously ingested in Iceberg tables, resulting in a large set of delete files that track changes in data files. With this new feature, when you enable the Data Catalog optimizer, it constantly monitors table partitions and runs the compaction process for both data and delta or delete files and regularly commits the partial progress. The Data Catalog also has expanded support for heavily nested complex data and supports schema evolution as you reorder or rename columns.

In this post, we assessed the ingestion and query performance of simulated IoT data using AWS Glue Iceberg with auto compaction enabled. Our setup processed over 20 billion events, managing duplicates and late-arriving events, and employed a MoR approach for both ingestion/appends and deletions to evaluate the performance improvement and efficiency.

Overall, AWS Glue Iceberg with auto compaction proves to be a robust solution for managing high-throughput IoT data streams. These enhancements lead to faster data processing, shorter query times, and more efficient resource utilization, all of which are essential for any large-scale data ingestion and analytics pipeline.

For detailed setup instructions, see the GitHub repo.


About the Authors

Navnit Shukla serves as an AWS Specialist Solutions Architect with a focus on Analytics. He possesses a strong enthusiasm for assisting clients in discovering valuable insights from their data. Through his expertise, he constructs innovative solutions that empower businesses to arrive at informed, data-driven choices. Notably, Navnit Shukla is the accomplished author of the book titled Data Wrangling on AWS. He can be reached through LinkedIn.

Angel Conde Manjon is a Sr. PSA Specialist on Data & AI, based in Madrid, and focuses on EMEA South and Israel. He has previously worked on research related to data analytics and artificial intelligence in diverse European research projects. In his current role, Angel helps partners develop businesses centered on data and AI.

Amit Singh currently serves as a Senior Solutions Architect at AWS, specializing in analytics and IoT technologies. With extensive expertise in designing and implementing large-scale distributed systems, Amit is passionate about empowering clients to drive innovation and achieve business transformation through AWS solutions.

Sandeep Adwankar is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
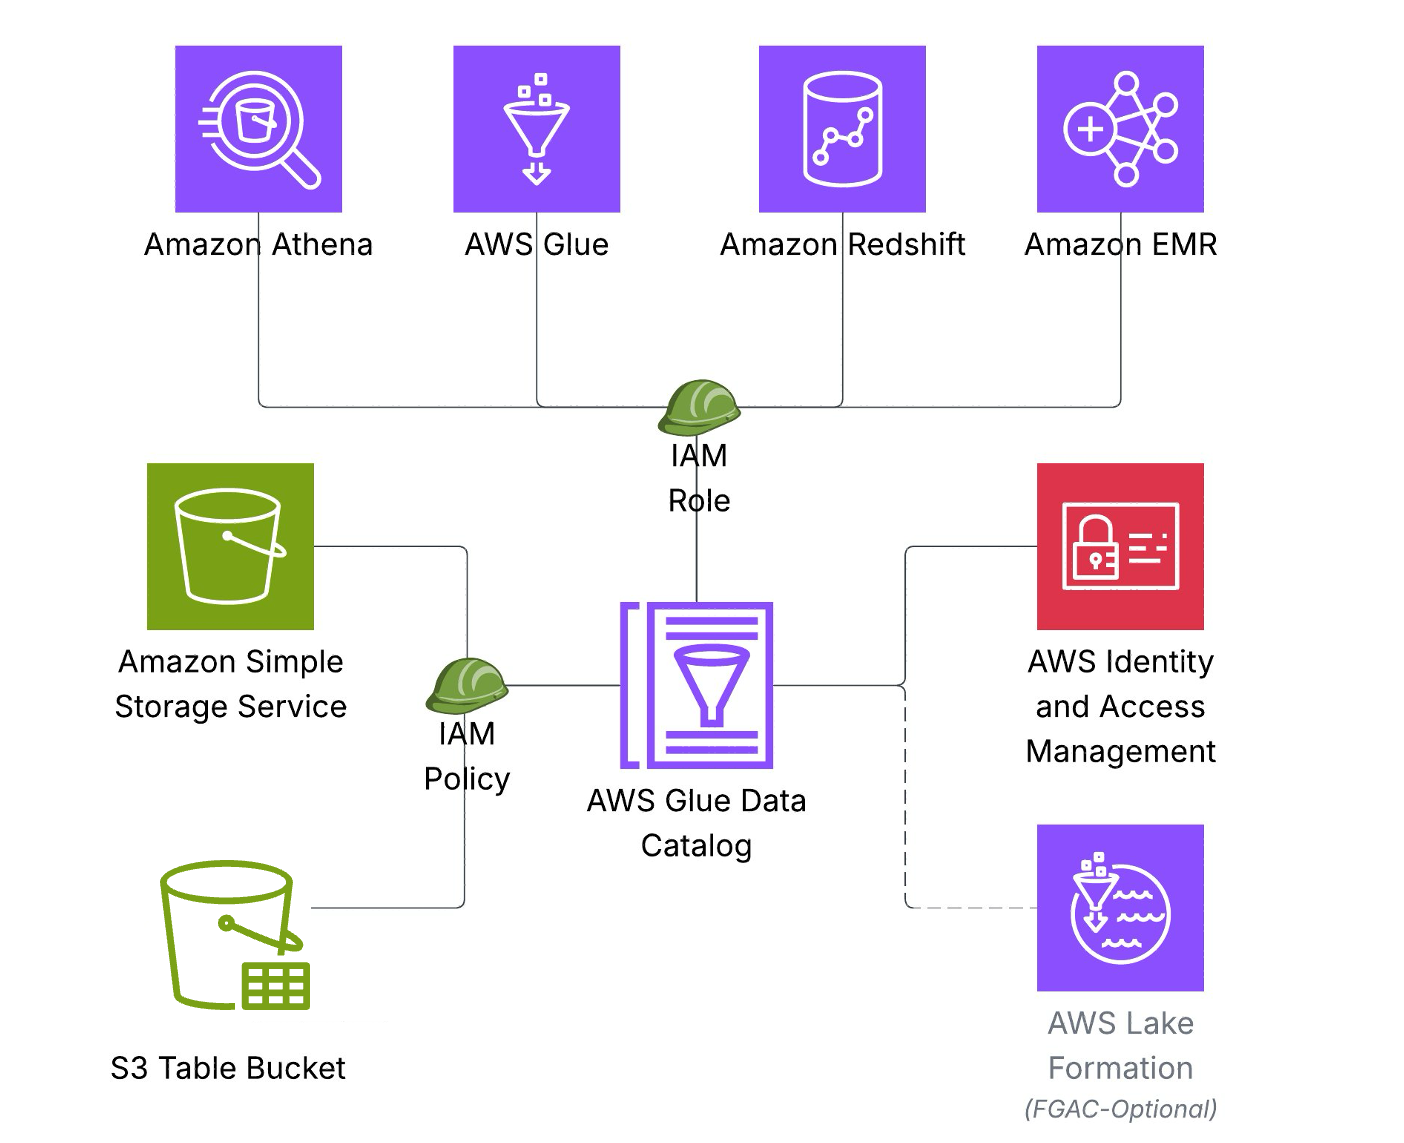
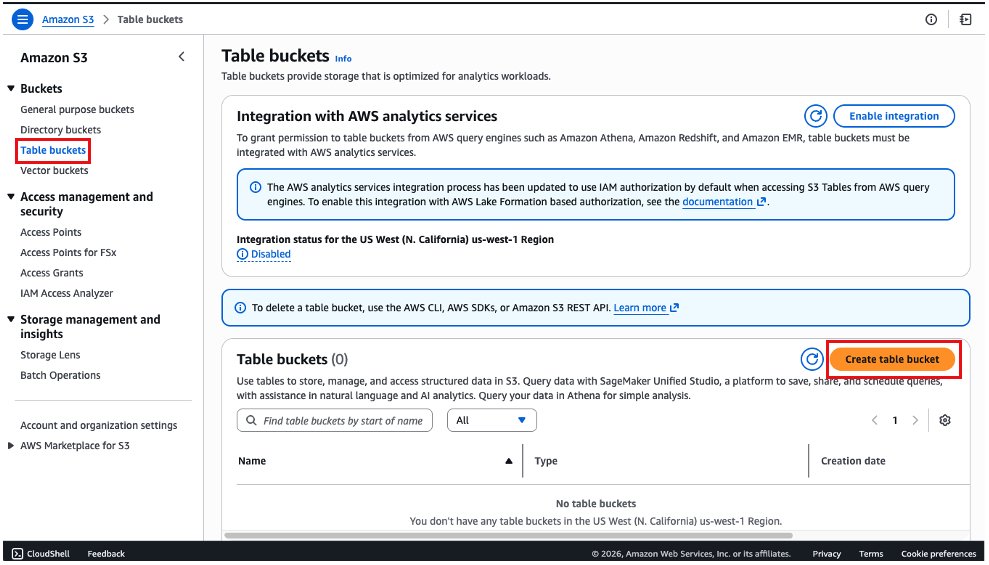
How DeNA Co., Ltd. accelerated anonymized data quality tests up to 100 times faster using Amazon Redshift Serverless and dbt

Post Syndicated from Momota Sasaki original https://aws.amazon.com/blogs/big-data/how-dena-co-ltd-accelerated-anonymized-data-quality-tests-up-to-100-times-faster-using-amazon-redshift-serverless-and-dbt/

This blog was co-authored by DeNA Co., Ltd. and Amazon Web Services Japan.

DeNA Co., Ltd. (DeNA) engages in a variety of businesses, from games and live communities to sports & the community and healthcare & medical, under our mission to delight people beyond their wildest dreams. Among these, the healthcare & medical business handles particularly sensitive data. To comply with their data policies for sensitive data, this healthcare & medical business set the following requirements for their data processing:
  • Process data in compliance with data policies – Mask or delete sensitive data as necessary to transform into anonymized data. Prevent the inclusion of invalid values in categorical data and process data without any data loss.
  • Conduct data quality tests on anonymized data in compliance with data policies – Conduct data quality tests to quickly identify and address data quality issues, maintaining high-quality data at all times.

This post introduces a case study where DeNA combined Amazon Redshift Serverless and dbt (dbt Core) to accelerate data quality tests in their business.

The challenge

Data quality tests require performing 1,300 tests on 10 TB of data monthly. Previously, DeNA ran Python-based batch jobs on Amazon Elastic Compute Cloud (Amazon EC2) to perform these data quality tests. As business and data volume grew over time, DeNA started to face the following challenges:

  • Performance – Data quality tests took days to weeks to complete because engineers hadn’t designed the batch jobs to handle big data.
  • Cost – Costs increased due to the batch job design, particularly for large datasets. The implementation required loading data into memory for processing. When handling large table data, DeNA needed to use large memory-optimized EC2 instances.
  • Maintainability – The batch job implementations varied significantly between engineers, leading to high maintenance overhead, because the required knowledge was siloed among individual engineers.

The switch to Redshift Serverless and dbt

To address these challenges, DeNA decided to adopt Redshift Serverless and dbt (an open source data transformation tool) for the following key reasons:

  • Scalable and cost-effective processing with Redshift Serverless
  • Standardized and maintainable data quality tests with dbt

This decision was made after careful comparison of alternative solutions. DeNA initially considered parallelizing the existing Python-based batch jobs but rejected this approach due to the high maintenance overhead and siloed knowledge associated with the batch jobs. Instead, DeNA decided to use dbt, which DeNA has been using in their healthcare & medical business, and connect it to an AWS service capable of large-scale distributed processing. dbt provides a SQL-first templating engine for repeatable and extensible data transformations, including a data tests feature, which allows verifying data models and tables against expected rules and conditions using SQL. By using dbt, DeNA could standardize the technical stack, implement data quality tests in maintainable SQL, and connect dbt to a managed service for scalable and cost-effective processing.

AWS offers several services that are compatible with dbt, including Amazon Redshift and AWS Glue. DeNA selected Redshift Serverless, primarily due to its serverless nature, optimal cost-performance, and the superior processing performance for structured data typical of a data warehouse service.

Solution overview

DeNA designed the following architecture using AWS serverless services.

The workflow consists of the following high-level steps and key design points:

  1. The source system stores the target data for the data quality tests in Amazon Simple Storage Service (Amazon S3). When new data files are added, Amazon EventBridge invokes an AWS Step Functions state machine (workflow). To make sure all files for target data are delivered, the source system stores a completion file in Amazon S3.
  2. dbt runs on Amazon Elastic Container Service (Amazon ECS) using AWS Fargate, an AWS serverless container service. DeNA selected Amazon ECS because it allows running dbt in a serverless, pay-per-use manner, and DeNA had prior experience developing and operating applications using Amazon ECS. To allow the containers to securely access Redshift Serverless, DeNA used the pass sensitive data to an ECS container feature to pass sensitive credentials that are stored in AWS Secrets Manager to the containers using an ECS task execution IAM role.
  3. DeNA segmented Redshift Serverless into separate workgroups for access control. Operation personnel may need to access the Redshift Serverless database using the Query Editor V2 to investigate issues with data quality tests, while maintaining strict access control. Redshift Serverless allows fine-grained access control to data by using database security features, similar to how the GRANT command is used in database products. However, in this workload, DeNA chose to use AWS Identity and Access Management (IAM) to control access to the workgroups at IAM level. This allowed DeNA to restrict access to specific Redshift Serverless workgroups based on users’ IAM roles, enabling unified management of authorization through IAM. Additionally, by separating the workgroups, DeNA could individually adjust Redshift Processing Units (RPUs) per workgroup, contributing to cost optimization.
  4. Amazon ECS sends execution logs of dbt running to Amazon CloudWatch Logs for observability. DeNA used metric filters to convert the logs into CloudWatch metrics, then created alarms based on these metrics. When triggered, these alarms invoke AWS Lambda functions using Amazon Simple Notification Service (Amazon SNS). The Lambda functions create result reports of dbt running and data quality tests and send them to an internal chat application. DeNA visualizes the results of data quality tests using the elementary CLI, a dbt-based data observability solution. This workflow enables even non-engineers to track data quality status effectively.

Outcomes

DeNA successfully addressed all the challenges they faced by designing the solution and migrating to a new platform:

  • Performance – Improved performance up to 100 times faster by reducing processing time from days or weeks to 1–2 hours. A certain data quality test that previously took 877 minutes now completes in 1 minute, thanks to the large-scale distributed processing capabilities of Redshift Serverless.
  • Cost – Reduced costs by 90% with AWS serverless services. Optimized expenses by incurring costs only for data quality tests.
  • Maintainability – Standardized the technical stack with dbt, eliminating siloed knowledge from custom programs. dbt’s data tests feature simplified the implementation of data quality tests. The elementary CLI improved the observability of data quality tests for non-engineers. AWS serverless services virtually eliminated the operational overhead for managing the workload infrastructure.

Conclusion

This post demonstrated how DeNA was able to securely and efficiently accelerate their data quality tests by combining Redshift Serverless and dbt. This combination is not only effective for DeNA’s use case but also applicable to various business use cases across different industries.

For more information on the combination of Redshift Serverless and dbt, refer to the following resources:


About the Author

Momota Sasaki is an Engineering Manager at DeSC Healthcare, a subsidiary of DeNA. He joined DeNA in 2021 and was seconded to DeSC Healthcare. Since then, he has been consistently involved in the healthcare business, leading and promoting the development and operation of the data platform.

Kaito Tawara is a Data Engineer at DeSC Healthcare, a subsidiary of DeNA, focusing on improving healthcare data platforms. After gaining experience in backend development for web systems and data science, he transitioned to data engineering. He joined DeNA in 2023 and was seconded to DeSC Healthcare. Currently, he works remotely from Nagoya-city, contributing to the enhancement of healthcare data platforms.

Shota Sato is an Analytics Specialist Solution Architect at AWS Japan, focusing on data analytics solutions powered by AWS for digital native business customers.

Build Write-Audit-Publish pattern with Apache Iceberg branching and AWS Glue Data Quality

Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/build-write-audit-publish-pattern-with-apache-iceberg-branching-and-aws-glue-data-quality/

Given the importance of data in the world today, organizations face the dual challenges of managing large-scale, continuously incoming data while vetting its quality and reliability. The importance of publishing only high-quality data can’t be overstated—it’s the foundation for accurate analytics, reliable machine learning (ML) models, and sound decision-making. Equally crucial is the ability to segregate and audit problematic data, not just for maintaining data integrity, but also for regulatory compliance, error analysis, and potential data recovery.

AWS Glue is a serverless data integration service that you can use to effectively monitor and manage data quality through AWS Glue Data Quality. Today, many customers build data quality validation pipelines using its Data Quality Definition Language (DQDL) because with static rules, dynamic rules, and anomaly detection capability, it’s fairly straightforward.

Apache Iceberg is an open table format that brings atomicity, consistency, isolation, and durability (ACID) transactions to data lakes, streamlining data management. One of its key features is the ability to manage data using branches. Each branch has its own lifecycle, allowing for flexible and efficient data management strategies.

This post explores robust strategies for maintaining data quality when ingesting data into Apache Iceberg tables using AWS Glue Data Quality and Iceberg branches. We discuss two common strategies to verify the quality of published data. We dive deep into the Write-Audit-Publish (WAP) pattern, demonstrating how it works with Apache Iceberg.
Strategy for managing data quality

When it comes to vetting data quality in streaming environments, two prominent strategies emerge: the dead-letter queue (DLQ) approach and the WAP pattern. Each strategy offers unique advantages and considerations.

  • The DLQ approach – Segregate problematic entries from high-quality data so that only clean data makes it into your primary dataset.
  • The WAP pattern – Using branches, segregate problematic entries from high-quality data so that only clean data is published in the main branch.

The DLQ approach

The DLQ strategy focuses on efficiently segregating high-quality data from problematic entries so that only clean data makes it into your primary dataset. Here’s how it works:

  1. As data streams in, it passes through a validation process
  2. Valid data is written directly to the table referred by downstream users
  3. Invalid or problematic data is redirected to a separate DLQ for later analysis and potential recovery

The following screenshot shows this flow.

bdb4341_0_1_dlq

Here are its advantages:

  • Simplicity – The DLQ approach is straightforward to implement, especially when there is only one writer
  • Low latency – Valid data is instantly available in the main branch for downstream consumers
  • Separate processing for invalid data – You can have dedicated jobs to process the DLQ for auditing and recovery purposes.

The DLQ strategy can present significant challenges in complex data environments. With multiple concurrent writers to the same Iceberg table, maintaining consistent DLQ implementation becomes difficult. This issue is compounded when different engines (for example, Spark, Trino, or Python) are used for writes because the DLQ logic may vary between them, making system maintenance more complex. Additionally, storing invalid data separately can lead to management overhead.

Additionally, for low-latency requirements, the processing validation step may introduce additional delays. This creates a challenge in balancing data quality with speed of delivery.

To solve those challenges in a reasonable way, we introduce the WAP pattern in the next section.

The WAP pattern

The WAP pattern implements a three-stage process:

  1. Write – Data is initially written to a staging branch
  2. Audit – Quality checks are performed on the staging branch
  3. Publish – Validated data is merged into the main branch for consumption

The following screenshot shows this flow.

bdb4341_0_2_wap

Here are its advantages:

  • Flexible data latency management – In the WAP pattern, the raw data is ingested to the staging branch without data validation, and then the high-quality data is ingested to the main branch with data validation. With this characteristic, there’s flexibility to achieve urgent, low-latency data handling on the staging branch and achieve high-quality data handling on the main branch.
  • Unified data quality management – The WAP pattern separates the audit and publish logic from the writer applications. It provides a unified approach to quality management, even with multiple writers or varying data sources. The audit phase can be customized and evolved without affecting the write or publish stages.

The primary challenge of the WAP pattern is the increased latency it introduces. The multistep process inevitably delays data availability for downstream consumers, which may be problematic for near real-time use cases. Furthermore, implementing this pattern requires more sophisticated orchestration compared to the DLQ approach, potentially increasing development time and complexity.

How the WAP pattern works with Iceberg

The following sections explore how the WAP pattern works with Iceberg.

Iceberg’s branching feature

Iceberg offers a branching feature for data lifecycle management, which is particularly useful for efficiently implementing the WAP pattern. The metadata of an Iceberg table stores a history of snapshots. These snapshots, created for each change to the table, are fundamental to concurrent access control and table versioning. Branches are independent histories of snapshots branched from another branch, and each branch can be referred to and updated separately.

When a table is created, it starts with only a main branch, and all transactions are initially written to it. You can create additional branches, such as an audit branch, and configure engines to write to them. Changes on one branch can be fast-forwarded to another branch using Spark’s fast_forward procedure, as shown in the following screenshot.

bdb4341_0_3_iceberg-branch

How to manage Iceberg branches

In this section, we cover the essential operations for managing Iceberg branches using SparkSQL. We’ll demonstrate how to use the branches, specifically, to create a new branch, write to and read from a specific branch, and set a default branch for a Spark session. These operations form the foundation for implementing the WAP pattern with Iceberg.

To create a branch, run the following SparkSQL query:

ALTER TABLE glue_catalog.db.tbl CREATE BRANCH audit

To specify a branch to be updated, use the glue_catalog.<database_name>.<table_name>.branch_<branch_name> syntax:

INSERT INTO glue_catalog.db.tbl.branch_audit VALUES (1, 'a'), (2, 'b');

To specify a branch to be queried, use the glue_catalog.<database_name>.<table_name>.branch_<branch_name> syntax:

SELECT * FROM glue_catalog.db.tbl.branch_audit;

To specify a branch for the entire Spark session scope, set the branch name to the Spark parameter spark.wap.branch. After this parameter is set, all queries will refer to the specified branch without explicit expression:

SET spark.wap.branch = audit

-- audit branch will be updated
INSERT INTO glue_catalog.db.tbl VALUES (3, 'c');

How to implement the WAP pattern with Iceberg branches

Using Iceberg’s branching feature, we can efficiently implement the WAP pattern with a single Iceberg table. Additionally, Iceberg characteristics such as ACID transactions and schema evolution are useful for handling multiple concurrent writers and varying data.
  1. Write – The data ingestion process switches branch from main and it commits updates to the audit branch, instead of the main branch. At this point, these updates aren’t accessible to downstream users who can only access the main branch.
  2. Audit – The audit process runs data quality checks on the data in the audit branch. It specifies which data is clean and ready to be provided.
  3. Publish – The audit process publishes validated data to the main branch with the Iceberg fast_forward procedure, making it available for downstream users.

This flow is shown in the following screenshot.

bdb4341_0_4_wap-w-iceberg-branch

By implementing the WAP pattern with Iceberg, we can obtain several advantages:

  • Simplicity – Iceberg branches can express multiple states of a table, such as audit and main, within one table. We can have unified data management even when handling multiple data contexts separately and uniformly.
  • Handling concurrent writers – Iceberg tables are ACID compliant, so consistent reads and writes are guaranteed even when multiple reader and writer processes run concurrently.
  • Schema evolution – If there are issues with the data being ingested, its schema may differ from the table definition. Spark supports dynamic schema merging for Iceberg tables. Iceberg tables can flexibly evolve their schema to write data with inconsistent schemas. By configuring the following parameters, when schema changes occur, new columns from the source are added to the target table with NULL values for existing rows. Columns present only in the target have their values set to NULL for new insertions or left unchanged during updates.
SET `spark.sql.iceberg.check-ordering` = false

ALTER TABLE glue_catalog.db.tbl SET TBLPROPERTIES (
    'write.spark.accept-any-schema'='true'
)
df.writeTo("glue_catalog.db.tbl").option("merge-schema","true").append()

As an intermediate wrap-up, the WAP pattern offers a robust approach to managing the balance between data quality and latency. With Iceberg branches, we can implement WAP pattern simply on single Iceberg table with handling concurrent writers and schema evolution.

Example use case

Suppose that a home monitoring system tracks room temperature and humidity. The system captures and sends the data to an Iceberg based data lake built on top of Amazon Simple Storage Service (Amazon S3). The data is visualized using matplotlib for interactive data analysis. For the system, issues such as device malfunctions or network problems can lead to partial or erroneous data being written, resulting in incorrect insights. In many cases, these issues are only detected after the data is sent to the data lake. Additionally, the correctness of such data is generally complicated.

To address these issues, the WAP pattern using Iceberg branches is applied for the system in this post. Through this approach, the incoming room data to the data lake is evaluated for quality before being visualized, and you make sure that only qualified room data is used for further data analysis. With the WAP pattern using the branches, you can achieve effective data management and promote data quality in downstream processes. The solution is demonstrated using AWS Glue Studio notebook, which is a managed Jupyter Notebook for interacting with Apache Spark.

Prerequisites

The following prerequisites are necessary for this use case:

Set up resources with AWS CloudFormation

First, you use a provided AWS CloudFormation template to set up resources to build Iceberg environments. The template creates the following resources:

  • An S3 bucket for metadata and data files of an Iceberg table
  • A database for the Iceberg table in AWS Glue Data Catalog
  • An AWS Identity and Access Management (IAM) role for an AWS Glue job

Complete the following steps to deploy the resources.

  1. Choose Launch stack.

Launch Button

  1. For the Parameters, IcebergDatabaseName is set by default. You can also change the default value. Then, choose Next.
  2. Choose Next.
  3. Choose I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  4. Choose Submit.
  5. After the stack creation is complete, check the Outputs The resource values are used in the following sections.

Next, configure the Iceberg JAR files to the session to use the Iceberg branch feature. Complete the following steps:

  1. Select the following JAR files from the Iceberg releases page and download these JAR files on your local machine:
    1. 1.6.1 Spark 3.3_with Scala 2.12 runtime Jar
    2. 1.6.1 aws-bundle Jar
  2. Open the Amazon S3 console and select the S3 bucket you created through the CloudFormation stack. The S3 bucket name can be found on the CloudFormation Outputs tab.
  3. Choose Create folder and create the jars path in the S3 bucket.
  4. Upload the two downloaded JAR files to s3://<IcebergS3Bucket>/jars/ from the S3 console.

Upload a Jupyter Notebook on AWS Glue Studio

After launching the CloudFormation stack, you create an AWS Glue Studio notebook to use Iceberg with AWS Glue. Complete the following steps.

  1. Download wap.ipynb.
  2. Open AWS Glue Studio console.
  3. Under Create job, select Notebook.
  4. Select Upload Notebook, choose Choose file, and upload the notebook you downloaded.
  5. Select the IAM role name, such as IcebergWAPGlueJobRole, that you created through the CloudFormation stack. Then, choose Create notebook.
  6. For Job name at the left top of the page, enter iceberg_wap.
  7. Choose Save.

Configure Iceberg branches

Start by creating an Iceberg table that contains a room temperature and humidity dataset. After creating the Iceberg table, create branches that are used for performing the WAP practice. Complete the following steps:
  1. On the Jupyter Notebook that you created in Upload a Jupyter Notebook on AWS Glue Studio, run the following cell to use Iceberg with Glue. %additional_python_modules pandas==2.2 is used to visualize the temperature and humidity data in the notebook with pandas. Before running the cell, replace <IcebergS3Bucket> with the S3 bucket name where you uploaded the Iceberg JAR files.
bdb4341_1_session-config

  1. Initialize the SparkSession by running the following cell. The first three settings, starting with spark.sql, are required to use Iceberg with Glue. The default catalog name is set to glue_catalog using spark.sql.defaultCatalog. The configuration spark.sql.execution.arrow.pyspark.enabled is set to true and is used for data visualization with pandas.

bdb4341_2_sparksession-init

  1. After the session is created (the notification Session <Session Id> has been created. will be displayed in the notebook), run the following commands to copy the temperature and humidity dataset to the S3 bucket you created through the CloudFormation stack. Before running the cell, replace <IcebergS3Bucket> with the name of the S3 bucket for Iceberg, which you can find on the CloudFormation Outputs tab.
!aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-4341/data/part-00000-fa08487a-43c2-4398-bae9-9cb912f8843c-c000.snappy.parquet s3://<IcebergS3Bucket>/src-data/current/ 
!aws s3 cp s3://aws-blogs-artifacts-public/artifacts/BDB-4341/data/new-part-00000-e8a06ab0-f33d-4b3b-bd0a-f04d366f067e-c000.snappy.parquet s3://<IcebergS3Bucket>/src-data/new/
  1. Configure the data source bucket name and path (DATA_SRC), Iceberg data warehouse path (ICEBERG_LOC), and database and table names for an Iceberg table (DB_TBL). Replace <IcebergS3Bucket> with the S3 bucket from the CloudFormation Outputs tab.
  2. Read the dataset and create the Iceberg table with the dataset using the Create Table As Select (CTAS) query.

bdb4341_3_ctas

  1. Run the following code to display the temperature and humidity data for each room in the Iceberg table. Pandas and matplotlib are used to visualize the data for each room. The data from 10:05 to 10:30 is displayed in the notebook, as shown in the following screenshot, with each room showing approximately 25°C for temperature (displayed as the blue line) and 52% for humidity (displayed as the orange line).
import matplotlib.pyplot as plt
import pandas as pd

CONF = [
    {'room_type': 'myroom', 'cols':['current_temperature', 'current_humidity']},
    {'room_type': 'living', 'cols':['current_temperature', 'current_humidity']},
    {'room_type': 'kitchen', 'cols':['current_temperature', 'current_humidity']}
]

fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL} WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 60)
    plt.yticks([tick for tick in range(10, 60, 10)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt

bdb4341_4_vis-1

  1. You create Iceberg branches by running the following queries before writing data into the Iceberg table. You can create an Iceberg branch by the ALTER TABLE db.table CREATE BRANCH <branch_name> query.
ALTER TABLE iceberg_wap_db.room_data CREATE BRANCH stg
ALTER TABLE iceberg_wap_db.room_data CREATE BRANCH audit

Now, you’re ready to build the WAP pattern with Iceberg.

Build WAP pattern with Iceberg

Use the Iceberg branches created earlier to implement the WAP pattern. You start writing the newly incoming temperature and humidity data including erroneous values to the stg branch in the Iceberg table.

Write phase: Write incoming data into the Iceberg stg branch

To write the incoming data into the stg branch in the Iceberg table, complete the following steps:

  1. Run the following cell and write the data into Iceberg table.

bdb4341_5_write

  1. After the records are written, run the following code to visualize the current temperature and humidity data in the stg On the following screenshot, notice that new data was added after 10:30. The output shows incorrect readings, such as around 100°C for temperature between 10:35 and 10:52 in the living room.
fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room_stg = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL}.branch_stg WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room_stg.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 110)
    plt.yticks([tick for tick in range(10, 110, 30)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt

bdb4341_6_vis-2

The new temperature data including erroneous records was written to the stg branch. This data isn’t visible to the downstream side because it hasn’t been published to the main branch. Next, you evaluate the data quality in the stg branch.

Audit phase: Evaluate the data quality in the stg branch

In this phase, you evaluate the quality of the temperature and humidity data in the stg branch using AWS Glue Data Quality. Then, the data that doesn’t meet the criteria is filtered out based on the data quality rules, and the qualified data is used to update the latest snapshot in the audit branch. Start with the data quality evaluation:

  1. Run the following code to evaluate the current data quality using AWS Glue Data Quality. The evaluation rule is defined in DQ_RULESET, where the normal temperature range is set between −10 and 50°C based on the device specifications. Any values out of this range are considered erroneous in this scenario.
from awsglue.context import GlueContext
from awsglue.transforms import SelectFromCollection
from awsglue.dynamicframe import DynamicFrame
from awsgluedq.transforms import EvaluateDataQuality
DQ_RULESET = """Rules = [ ColumnValues "current_temperature" between -10 and 50 ]"""


dyf = DynamicFrame.fromDF(
    dataframe=spark.sql(f"SELECT * FROM {DB_TBL}.branch_stg"),
    glue_ctx=GlueContext(spark.sparkContext),
    name='dyf')

dyfc_eval_dq = EvaluateDataQuality().process_rows(
    frame=dyf,
    ruleset=DQ_RULESET,
    publishing_options={
        "dataQualityEvaluationContext": "dyfc_eval_dq",
        "enableDataQualityCloudWatchMetrics": False,
        "enableDataQualityResultsPublishing": False,
    },
    additional_options={"performanceTuning.caching": "CACHE_NOTHING"},
)

# Show DQ results
dyfc_rule_outcomes = SelectFromCollection.apply(
    dfc=dyfc_eval_dq,
    key="ruleOutcomes")
dyfc_rule_outcomes.toDF().select('Outcome', 'FailureReason').show(truncate=False)
  1. The output shows the result of the evaluation. It displays Failed because some temperature data, such as 105°C, is out of the normal temperature range of −10 to 50°C.
+-------+------------------------------------------------------+
|Outcome|FailureReason                                         |
+-------+------------------------------------------------------+
|Failed |Value: 105.0 does not meet the constraint requirement!|
+-------+------------------------------------------------------+
  1. After the evaluation, filter out the incorrect temperature data in the stg branch, then update the latest snapshot in the audit branch with the valid temperature data.

bdb4341_7_write-to-audit

Through the data quality evaluation, the audit branch in the Iceberg table now contains the valid data, which is ready for downstream use.

Publish phase: Publish the valid data to the downstream side

To publish the valid data in the audit branch to main, complete the following steps:

  1. Run the fast_forward Iceberg procedure to publish the valid data in the audit branch to the downstream side.

bdb4341_8_publish

  1. After the procedure is complete, review the published data by querying the main branch in the Iceberg table to simulate the query from the downstream side.
fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room_main = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL} WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room_main.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 60)
    plt.yticks([tick for tick in range(10, 60, 10)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt

The query result shows only the valid temperature and humidity data that has passed the data quality evaluation.

bdb4341_9_vis-3

In this scenario, you successfully managed data quality by applying the WAP pattern with Iceberg branches. The room temperature and humidity data, including any erroneous records, was first written to the staging branch for quality evaluation. This approach prevented erroneous data from being visualized and leading to incorrect insights. After the data was validated by AWS Glue Data Quality, only valid data was published to the main branch and visualized in the notebook. Using the WAP pattern with Iceberg branches, you can make sure that only validated data is passed to the downstream side for further analysis.

Clean up resources

To clean up the resources, complete the following steps:

  1. On the Amazon S3 console, select the S3 bucket aws-glue-assets-<ACCOUNT_ID>-<REGION> where the Notebook file (iceberg_wap.ipynb) is stored. Delete the Notebook file located in the notebook path.
  2. Select the S3 bucket you created through the CloudFormation template. You can obtain the bucket name from IcebergS3Bucket key on the CloudFormation Outputs tab. After selecting the bucket, choose Empty to delete all objects.
  3. After you confirm the bucket is empty, delete the CloudFormation stack iceberg-wap-baseline-resources.

Conclusion

In this post, we explored common strategies for maintaining data quality when ingesting data into Apache Iceberg tables. The step-by-step instructions demonstrated how to implement the WAP pattern with Iceberg branches. For use cases requiring data quality validation, the WAP pattern provides the flexibility to manage data latency even with concurrent writer applications without impacting downstream applications.


About the Authors

Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Sotaro Hikita is a Solutions Architect. He supports customers in a wide range of industries, especially the financial industry, to build better solutions. He is particularly passionate about big data technologies and open source software.

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.