Tag Archives: AWS Elastic Disaster Recovery (DRS)

Automating the full AWS DRS agent lifecycle: Install, heal, and offboard

Post Syndicated from Manisha Yadav original https://aws.amazon.com/blogs/architecture/automating-the-full-aws-drs-agent-lifecycle-install-heal-and-offboard/

If you protect a large Amazon Elastic Compute Cloud (Amazon EC2) fleet with AWS Elastic Disaster Recovery (AWS DRS), you manage the AWS Replication Agent across its whole lifecycle. You install it, keep it healthy and registered, and remove it cleanly when a server leaves disaster recovery (DR) scope. An enterprise IT customer with more than 300 Linux and Windows instances in DR scope ran into two of these problems while planning and validating a scheduled DR drill. Some agents had stalled after a network change, and some descoped servers were still replicating and adding to the bill. A server with a stalled agent can’t meet your recovery point objective (RPO), the maximum data loss you can accept after a disruption. The customer’s team checked replication status in the AWS DRS console before each drill, so a problem that started between drills could go unnoticed until the next one.

Working with that customer, we automated the install, heal, and offboard phases of the lifecycle. Most of the design choices in this post came from fixing those two problems. Each phase runs as an AWS Systems Manager (SSM) Automation document, started by Amazon EventBridge or on a schedule. A single EC2 tag decides which phase applies to an instance. Because the logic lives in the Automation documents, there are no AWS Lambda functions to maintain. When you take an instance out of scope, the automation records whether replication billing actually stopped.

You can find the SSM Automation documents, AWS Identity and Access Management (IAM) policies, and deployment scripts in the aws-samples/sample-drs-agent-lifecycle-automation GitHub repository.

Solution overview

You apply a DR tag to each EC2 instance, and its value (yes, pause, or no) tells the automation what to do. Three SSM Automation documents divide the work. Onboarding installs and repairs the agent and keeps registration healthy. Healing responds when replication stalls, and offboarding runs teardown when you descope an instance.

AWS Systems Manager State Manager runs onboarding on a 30-minute schedule against tagged instances. Amazon EventBridge triggers healing when AWS DRS reports a stalled server, and offboarding when the DR tag changes. The automation runs primarily in your source AWS Region and calls the DR Region only where AWS DRS requires it.

Prerequisites

To deploy this solution, you need:

  • An AWS account with administrative access.
  • Two AWS Regions configured: a source Region (where your EC2 instances run) and a DR Region (where AWS DRS replicates to).
  • AWS Elastic Disaster Recovery initialized in both the source Region (for failback) and the DR Region (for replication).
  • Network connectivity between Regions with TCP 443 (AWS DRS API and Amazon Simple Storage Service (Amazon S3)) and TCP 1500 (replication data) open. For private connectivity, use AWS Transit Gateway or VPC peering. Public endpoints are also supported.
  • (Optional) Amazon Virtual Private Cloud (Amazon VPC) endpoints for AWS DRS and Amazon S3 in the DR Region, if using private connectivity.
  • IAM permissions to deploy AWS CloudFormation stacks that create named IAM roles (CAPABILITY_NAMED_IAM), Amazon EventBridge rules, and a State Manager association, and to register SSM Automation documents. You also need iam:PassRole on DRS-Automation-Role, because the Amazon EventBridge rules and the State Manager association use that role.
  • AWS Command Line Interface (AWS CLI) installed and configured.
  • An instance profile on each source EC2 instance with the AWSElasticDisasterRecoveryAgentInstallationPolicy and AmazonSSMManagedInstanceCore managed policies, so that each instance is managed by Systems Manager. If your instances already have an instance profile, attach both policies to its role.
  • An existing Amazon Simple Notification Service (Amazon SNS) topic for notifications.
  • (Optional) An existing Amazon S3 bucket for audit reports.
  • Git, Bash 4 or later, and yq. The deployment scripts use yq to read config.yaml. macOS includes Bash 3.2, so install a newer version, for example with Homebrew.

You don’t need to create the automation’s IAM roles yourself. The CloudFormation templates create DRS-Automation-Role (which runs every lifecycle action) and DRS-EventBridge-Forward-Role (deployed with the DR Region stack), along with the Amazon EventBridge rules in both Regions and the State Manager association. Amazon CloudWatch metrics are published automatically.

One tag controls the entire lifecycle

After you deploy the solution, the value of the DR tag on each EC2 instance determines what the automation does:

DR value State What happens
yes Protected Agent is installed, failback tag applied, health maintained every 30 minutes
pause Quiesced Agent stays installed, stalled alerts suppressed, offboarding blocked
no or deleted Descoped Replication stopped, source server deleted, agent uninstalled
Anything else (for example, DR=maybe, DR=true) Misconfigured Fail-safe: automation skips the instance and logs a SKIPPED_MISCONFIGURED status. No install, no heal, no teardown, preventing an unrecognized value from triggering the wrong action

The tag value is normalized (trimmed and lowercased) before evaluation. A value like DR=Yes normalizes to DR=yes and matches correctly.

Three SSM Automation documents divide the lifecycle:

  • DRS-Agent-Onboard runs every 30 minutes through State Manager against tag:DR=yes instances. It installs or repairs the agent, applies the AWSDRS:AllowLaunchingIntoThisInstance tag, and validates AWS DRS registration. The tag tells AWS DRS to launch recovery onto the original instance during failback and acts as the drift-correction backstop. State Manager re-evaluates tagged instances every 30 minutes. Each run catches instances that lost the Replication Agent, newly tagged instances that aren’t onboarded yet, and earlier runs that failed silently.
  • DRS-Agent-Heal fires when Amazon EventBridge receives a replication-stalled event (cross-Region forwarded from the DR Region). The rule filters on the STALLED state, so recovery transitions don’t trigger unnecessary runs. It inspects the replication error to distinguish agent-side failures from infrastructure issues. For agent problems, it restarts the service first, then reinstalls in place only if the restart doesn’t fix it. For infrastructure-caused stalls, it escalates to operators through Amazon SNS.
  • DRS-Agent-Offboard fires when Amazon EventBridge detects a DR tag change or deletion. The offboarding document first verifies safeguards: a tag re-check, a terminated-instance guard, and an optional approval gate. After those pass, it records replication state and stops replication. It then disconnects the source server, deletes it, uninstalls the Replication Agent, and removes the tags.

How the components connect

The solution operates primarily in the source Region. Cross-Region calls happen only where AWS DRS requires them (registration checks and teardown API calls target the DR Region).

The following diagram shows how the automation components connect across the source and DR Regions. State Manager and Amazon EventBridge operate in the source Region; AWS DRS replication and the stall-forwarding rule run in the DR Region.
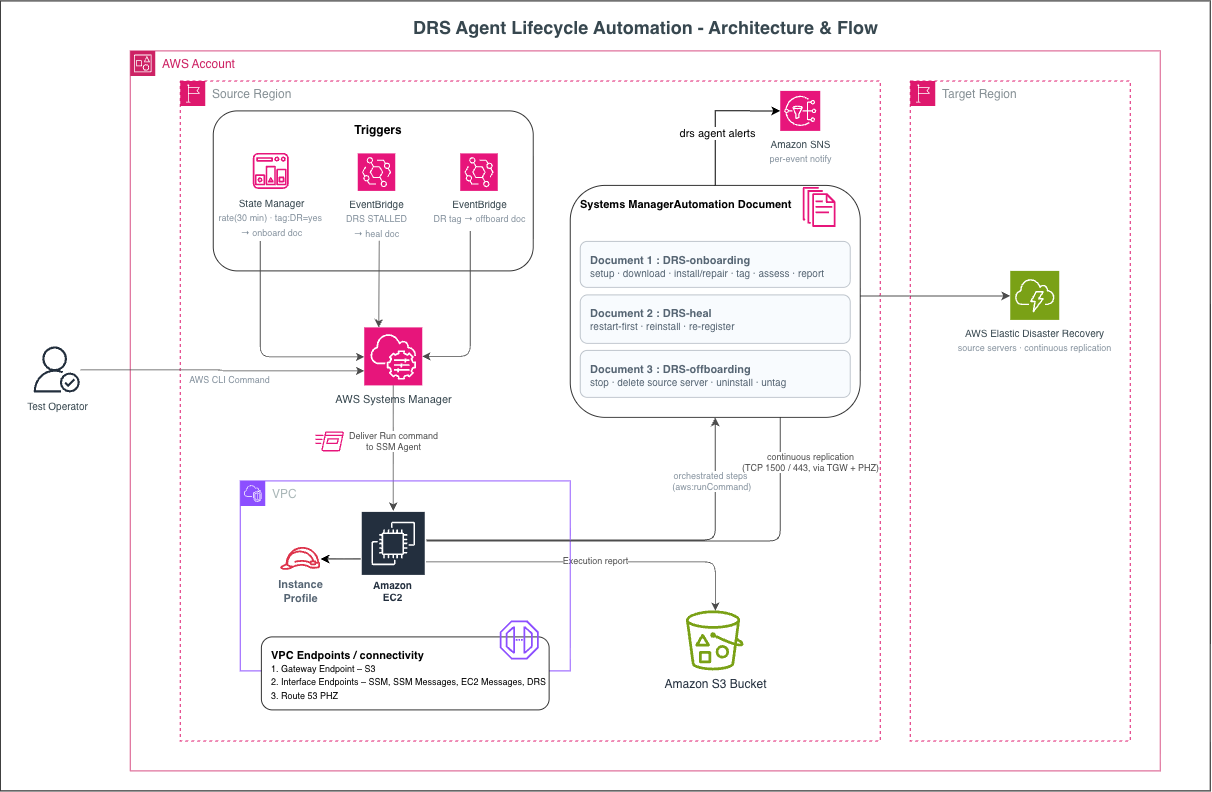
State Manager and EventBridge in the source Region connecting to AWS DRS replication in the DR Region

Figure 1: AWS DRS agent lifecycle automation architecture across the source and DR Regions

In the source Region, State Manager runs the onboarding document every 30 minutes, and Amazon EventBridge rules start the heal and offboarding documents when their events arrive. AWS Systems Manager Parameter Store holds the DR-event stand-down flag (/drs/control/event-in-progress). The DRS-Automation-Role IAM role runs every automation step. Amazon SNS delivers alerts, Amazon S3 stores per-event audit reports, and Amazon CloudWatch captures outcome metrics.

In the DR Region, AWS DRS manages source server registration and ongoing replication. AWS DRS emits replication events only in the DR Region, where the source servers are registered. An Amazon EventBridge forwarding rule filters replication-stalled events by the STALLED state. It then sends them to the source Region for healing. Staging subnets and Amazon Elastic Block Store (Amazon EBS) volumes, managed by AWS DRS, support the replication infrastructure.

For networking, AWS Transit Gateway (which connects VPCs across Regions) carries TCP 443 (AWS DRS API and S3) and TCP 1500 (replication data) between Regions. Amazon VPC endpoints for AWS DRS and S3 keep traffic on the AWS backbone without internet exposure. An Amazon Route 53 Private Hosted Zone (for DNS resolution within your VPC) resolves endpoint names to private IPs. This removes the need for --endpoint installer flags and protects failback compatibility.

Tag and rule examples

Run these commands after you deploy the solution. Tag an instance for protection:

aws ec2 create-tags --resources i-0abc123def456 --tags Key=DR,Value=yes

Descope an instance (triggers offboarding):

aws ec2 create-tags --resources i-0abc123def456 --tags Key=DR,Value=no

Or remove the tag entirely (also triggers offboarding):

aws ec2 delete-tags --resources i-0abc123def456 --tags Key=DR

The Amazon EventBridge rule that triggers offboarding matches this pattern:

{
  "source": ["aws.tag"],
  "detail-type": ["Tag Change on Resource"],
  "detail": {
    "changed-tag-keys": ["DR"],
    "service": ["ec2"],
    "resource-type": ["instance"]
  }
}

The Amazon EventBridge rule that triggers healing filters on the STALLED state so recovery transitions are ignored:

{
  "source": ["aws.drs"],
  "detail-type": ["DRS Source Server Data Replication Stalled Change"],
  "detail": {
    "state": ["STALLED"]
  }
}

Three layers protecting the RPO

The 15-minute RPO referenced throughout this post is a customer-configured target, not an AWS service guarantee. The architecture helps protect it with three complementary layers, each covering a different failure mode.

Layer 1: OS service auto-restart (seconds). The agent service uses systemd Restart=always on Linux and Windows Service Recovery. When the process stops, the OS brings it back automatically. On Linux, systemd restarts the service almost instantly. On Windows, the first recovery action fires after a configurable delay (30 seconds by default). This layer handles agent process crashes without any automation running.

Layer 2: Amazon EventBridge heal (minutes, not seconds). If the agent disappears or can’t maintain registration, AWS DRS detects the stall and emits a replication-stalled event in the DR Region. A forwarding rule filters on the STALLED state and sends it cross-Region to the source Region’s event bus. A matching receive rule triggers the heal document.

The heal document restarts the agent first (most stalls are transient). If restart fails, it re-runs the installer in place, preserving driver state to avoid a full-disk rescan. The restart path is the faster of the two, and total time depends on your environment and on AWS DRS stall-detection latency. The reinstall path takes longer because the agent must re-establish block-level tracking. Stall-detection latency also counts against the window, because lag must accumulate before the service marks a server as stalled.

Layer 3: State Manager backstop (up to 30 minutes). The onboarding document re-evaluates DR=yes instances every 30 minutes, catching drift and edge cases that faster layers miss. This exceeds the 15-minute RPO target, so it functions as a safety net rather than the primary defense.

Layer 2 requires the Amazon EventBridge data plane in both Regions to be operational, while Layers 1 and 3 run entirely in the source Region.

Onboarding: How ongoing convergence works

State Manager targets tag:DR=yes. Instances that already have the tag and instances you tag later are included automatically, without manual registration.

The onboarding document is idempotent. It skips healthy, registered instances. For instances that need work, it checks the stand-down flag and instance state, validates the operating system (Linux or Windows), and flags unsupported architectures as TAGGED_UNSUPPORTED. If AutoInstallEnabled is false, the run is audit-only.

For actual installs, a concurrency lock (flock on Linux, a named mutex on Windows) prevents races when multiple automation runs overlap on the same instance. This lock is built into the documents and needs no configuration. The State Manager association sets MaxConcurrency to 10 and MaxErrors to 100% in templates/state-manager-association.yaml. MaxConcurrency limits how many instances are processed at once. With MaxErrors at 100%, a failure on one instance doesn’t stop the run for the rest of the fleet. For larger fleets, raise MaxConcurrency gradually and watch for AWS DRS API throttling.

The failback tag (AWSDRS:AllowLaunchingIntoThisInstance) is applied only when the agent is confirmed present. Registration is assessed cross-Region, and if an instance stays in PENDING_REGISTRATION beyond a configurable threshold (default: 3 runs), the document escalates through Amazon SNS. Each execution writes an S3 audit record and emits a CloudWatch metric.

Healing agent issues within RPO

The heal document reads the source server ARN from the event and looks up the matching EC2 instance ID with drs:DescribeSourceServers in the DR Region. It then checks the stand-down flag and the tag state. Values other than yes suppress the heal with no action and no alert.

If restart doesn’t resolve the issue, the automation re-runs the installer in place as a fallback. It doesn’t uninstall first, so the existing replication driver stays intact where possible. Reinstallation can trigger a block-level rescan whose duration scales with total disk size. On large volumes, this might temporarily exceed the RPO window while the rescan completes.

Not every stall is an agent problem. Bandwidth throttling, undersized replication servers, or staging-area disk issues can also cause stalls. The automation escalates these non-agent stalls to your operators through Amazon SNS rather than attempting agent remediation. If the Replication Agent is still not functioning after reinstall, you receive a HEAL_FAILED notification with diagnostic details.

Only the AWS DRS agent service is restarted, not the EC2 instance itself. Your workloads keep running without interruption.

Offboarding with honest billing status

When you set DR=no or delete the tag, Amazon EventBridge fires a Tag Change on Resource event. The offboarding document applies several safeguards before teardown.

Terminated-instance guard: EC2 termination strips tags, generating the same event as a deliberate descope. The document sends an alert and stops. It doesn’t delete the source server, which contains the recovery point.

Tag re-check: If the tag has been restored, the document exits.

Approval gate: If AutoOffboardEnabled is false, the document sends a notification and stops.

State recording: Before modifying resources, it captures replication state, lag duration, and last snapshot time.

Recovery-instance check: Before completing teardown, the offboarding document checks for active recovery instances. If found, it flags them in the audit report and sends an SNS alert. Recovery instances incur separate EC2 billing that persists after source server deletion.

Adaptive retry: A maximum of 10 attempts with exponential backoff handles API throttling during bulk descope.

After teardown, the document checks what actually succeeded:

Outcome Meaning
COMPLETED Source server deleted, billing halted
BILLING_STOPPED_ORPHAN Replication stopped but delete didn’t succeed. Operator must manually delete.
FAILED stop_replication didn’t succeed. Billing might still be active. Operator review recommended.
NO_SERVER Instance was not registered as an AWS DRS source server. Clean no-op.

Because each outcome reflects what actually succeeded, you know whether replication billing has stopped or whether a source server needs manual follow-up.

Security: Least-privilege IAM roles

The solution creates two IAM roles and relies on one that you provide. SSM Automation and Amazon EventBridge assume the DRS-Automation-Role to run all lifecycle actions. Its permissions cover SSM, EC2 tags, cross-Region AWS DRS calls, SNS, S3, Parameter Store, and iam:PassRole on itself. The iam:PassRole permission only allows passing this role to Systems Manager. Run Command is limited to instances tagged DR=yes. In the DR Region, the DRS-EventBridge-Forward-Role can only put events on the source Region’s default event bus.

On each EC2 instance, the instance profile from the prerequisites lets the Replication Agent and SSM Agent reach their services. The automation stores no long-lived credentials. Each role receives temporary credentials when it’s assumed. When you use private connectivity, cross-Region traffic stays on Transit Gateway and VPC endpoints.

Deploy the solution

Start in audit mode, where the onboarding document reports what it would install without changing any instance and offboarding sends a notification instead of running teardown. Review the audit reports, then turn on installation for a small set of instances before you scale to the full fleet.

To configure config.yaml

Clone the repository and change to its directory:

git clone https://github.com/aws-samples/sample-drs-agent-lifecycle-automation.git
cd sample-drs-agent-lifecycle-automation

The deployment scripts read your settings from config.yaml in the root of the repository. Set the values in the following sample before you deploy. The file in the repository also sets document names and stack names. Keep those at their defaults, because the commands in this post use the default names.

# Region configuration
source_region: us-west-1        # Region where your EC2 instances run
dr_region: us-east-2            # Region where AWS DRS replicates to
account_id: "111122223333"      # Your AWS account ID

# Observability
sns_topic_name: drs-alerts      # Existing SNS topic for notifications
amzn-s3-demo-audit_bucket: ""           # Existing S3 bucket for audit reports; empty turns off audit reports
cloudwatch_namespace: DRSAutomation

# Automation toggles (start in audit mode)
auto_install_enabled: "false"   # false = report only; true = install and repair agents
auto_offboard_enabled: "false"  # false = notify only; true = tear down on descope

# Tag configuration
dr_tag_key: DR
dr_protected_value: "yes"
dr_descope_value: "no"

# Stand-down control and schedule
stand_down_parameter: /drs/control/event-in-progress
schedule_rate: "rate(30 minutes)"

The following table describes the values you’re most likely to change.

Parameter Required Description
source_region Yes Region that hosts your EC2 instances and the automation
dr_region Yes Region where AWS DRS replicates to
account_id Yes AWS account that hosts the automation
sns_topic_name Yes Name of an existing SNS topic in the source Region
amzn-s3-demo-audit_bucket No Existing S3 bucket for JSON audit reports. Leave empty to skip them
auto_install_enabled No Set to false to report only, or true to install and repair agents
auto_offboard_enabled No Set to false to notify only, or true to run teardown when you descope an instance
dr_tag_key No EC2 tag key that controls the lifecycle (default DR)

To deploy the solution

The following steps deploy each component separately so you can see what each one creates. Run the commands from the root of the cloned repository. Replace the example account ID (111122223333) and Regions (us-west-1 and us-east-2) with your own values.

To deploy everything in one command instead, run ./scripts/deploy.sh after you edit config.yaml, and then go to the confirmation commands after step 6. The script prints the status of every stack when it finishes. Without yq, it falls back to built-in defaults, including a placeholder account ID. Use either the script or the individual steps, not both.

  1. Deploy the IAM role stack. The template creates a role with an explicit name (DRS-Automation-Role), so CAPABILITY_NAMED_IAM is required.
    aws cloudformation deploy \
      --template-file templates/iam-roles.yaml \
      --stack-name drs-automation-iam \
      --capabilities CAPABILITY_NAMED_IAM \
      --region us-west-1 \
      --parameter-overrides \
        AccountId=111122223333 \
        SourceRegion=us-west-1 \
        DRRegion=us-east-2 \
        SNSTopicName=drs-alerts

  2. Register the three SSM Automation documents. The script reads source_region from config.yaml and creates the documents from the documents/ folder on the first run. On later runs, it publishes a new default version of any document that changed.
    ./scripts/register-documents.sh

  3. Deploy the Amazon EventBridge rules in the source Region. This stack creates the tag-change rule that starts offboarding and the rule that starts healing. It uses the existing DRS-Automation-Role, so it doesn’t need CAPABILITY_NAMED_IAM.
    aws cloudformation deploy \
      --template-file templates/eventbridge-source.yaml \
      --stack-name drs-eventbridge-source \
      --region us-west-1 \
      --parameter-overrides \
        AutomationRoleArn=arn:aws:iam::111122223333:role/DRS-Automation-Role \
        TargetRegion=us-east-2 \
        SNSTopicArn=arn:aws:sns:us-west-1:111122223333:drs-alerts \
        AutoOffboardEnabled=false

  4. Deploy the forwarding rule in the DR Region. This stack creates DRS-EventBridge-Forward-Role, which lets the rule send stalled events to the source Region’s event bus, so CAPABILITY_NAMED_IAM is required.
    aws cloudformation deploy \
      --template-file templates/eventbridge-dr.yaml \
      --stack-name drs-eventbridge-dr \
      --capabilities CAPABILITY_NAMED_IAM \
      --region us-east-2 \
      --parameter-overrides \
        SourceRegion=us-west-1 \
        AccountId=111122223333

  5. Create the stand-down flag in Parameter Store with a value of false. The script reads the parameter name and Region from config.yaml and doesn’t overwrite an existing value.
    ./scripts/init-parameters.sh

    If you prefer not to use the script, run the following command instead:

    aws ssm put-parameter --name /drs/control/event-in-progress \
      --value false --type String --region us-west-1

  6. Deploy the State Manager association in audit mode. The association runs once as soon as it’s created and then every 30 minutes.
    aws cloudformation deploy \
      --template-file templates/state-manager-association.yaml \
      --stack-name drs-state-manager \
      --region us-west-1 \
      --parameter-overrides \
        AutomationRoleArn=arn:aws:iam::111122223333:role/DRS-Automation-Role \
        TargetRegion=us-east-2 \
        AutoInstallEnabled=false \
        SNSTopicArn=arn:aws:sns:us-west-1:111122223333:drs-alerts

To confirm the deployment, run the following commands:

aws cloudformation describe-stacks --region us-west-1 \
  --query "Stacks[?starts_with(StackName, 'drs-')].[StackName,StackStatus]" --output table

aws cloudformation describe-stacks --stack-name drs-eventbridge-dr --region us-east-2 \
  --query "Stacks[0].StackStatus" --output text

aws events list-rules --name-prefix DRS- --region us-west-1 --query "Rules[].Name"

aws events list-rules --name-prefix DRS- --region us-east-2 --query "Rules[].Name"

aws ssm list-documents --filters Key=Owner,Values=Self --region us-west-1 \
  --query "DocumentIdentifiers[?starts_with(Name, 'DRS-Agent-')].Name"

aws ssm get-parameter --name /drs/control/event-in-progress --region us-west-1 \
  --query "Parameter.Value" --output text

A successful deployment shows the following results:

  • All four stacks show CREATE_COMPLETE, or UPDATE_COMPLETE after a re-run.
  • The source Region lists the DRS-Tag-Change-Offboard and DRS-Stalled-Heal-Receive rules.
  • The DR Region lists the DRS-Stalled-Forward rule.
  • The source Region lists the DRS-Agent-Onboard, DRS-Agent-Heal, and DRS-Agent-Offboard documents.
  • The stand-down flag returns false.
  • In the AWS Systems Manager console, State Manager lists DRS-Agent-Onboard-Association.

When you’re ready to turn on installation, set auto_install_enabled: "true" in config.yaml and deploy the State Manager stack again with AutoInstallEnabled=true:

aws cloudformation deploy \
  --template-file templates/state-manager-association.yaml \
  --stack-name drs-state-manager \
  --region us-west-1 \
  --parameter-overrides \
    AutomationRoleArn=arn:aws:iam::111122223333:role/DRS-Automation-Role \
    TargetRegion=us-east-2 \
    AutoInstallEnabled=true \
    SNSTopicArn=arn:aws:sns:us-west-1:111122223333:drs-alerts

To turn on teardown, set auto_offboard_enabled: "true" and deploy the source Region Amazon EventBridge stack again with AutoOffboardEnabled=true:

aws cloudformation deploy \
  --template-file templates/eventbridge-source.yaml \
  --stack-name drs-eventbridge-source \
  --region us-west-1 \
  --parameter-overrides \
    AutomationRoleArn=arn:aws:iam::111122223333:role/DRS-Automation-Role \
    TargetRegion=us-east-2 \
    SNSTopicArn=arn:aws:sns:us-west-1:111122223333:drs-alerts \
    AutoOffboardEnabled=true

Safety guards prevent unintended actions

The following table lists the safety guards across the three automation documents. The stand-down flag and the tag value allow-list apply to every document. The terminated-instance guard and honest billing status protect offboarding, and the remaining guards protect onboarding and healing.

Guard Prevents
DR-event stand-down Acting during failover/failback
Terminated-instance guard Deleting a recovery point on instance termination
Reverse-direction detect Overwriting an AWS DRS-managed failback agent
Concurrency lock Race conditions from overlapping runs
AutoInstallEnabled gate Unintended installs in audit-first deployments
OS pre-check Running installer on incompatible operating system
Honest billing status Reporting “billing stopped” when teardown partially completed
Tag value allow-list A typo triggering the wrong lifecycle action
Agent-presence-gated tagging Applying failback tag to an agent-less instance

To pause the automation during a declared DR event:

aws ssm put-parameter --name /drs/control/event-in-progress \
  --value true --type String --overwrite --region us-west-1

To resume after the event:

aws ssm put-parameter --name /drs/control/event-in-progress \
  --value false --type String --overwrite --region us-west-1

Monitoring and observability

The three SSM Automation documents produce telemetry across three channels, each tuned for a different audience.

Amazon SNS notifications go to the on-call team. Onboarding stays quiet unless an instance needs intervention. Heal notifies on both success and intervention-needed, because a successful auto-heal still tells you a real issue occurred and was resolved. Offboarding sends a notification at each stage: start, complete, orphan, incomplete, and approval-needed.

Amazon S3 audit reports serve compliance and troubleshooting. One JSON object per lifecycle event at s3://<amzn-s3-demo-audit_bucket>/drs/<account>/<instance>/<event>-<timestamp>.json captures instance ID, host name, platform, source server ID, status, and pre-teardown replication state. To control storage costs, add a lifecycle rule to the bucket (for example, expire objects under drs/ after 90 days).

Amazon CloudWatch metrics power fleet dashboards. An Outcome metric (1=handled, 0=needs attention) dimensioned by event type provides at-a-glance fleet health.

Clean up

Removing the automation doesn’t stop replication. Instances tagged DR=yes keep replicating until you stop replication through the AWS DRS console or API. To remove the automation infrastructure, run the following commands:

  1. Delete the State Manager association and the source Region Amazon EventBridge stacks.
    aws cloudformation delete-stack --stack-name drs-state-manager --region us-west-1
    aws cloudformation delete-stack --stack-name drs-eventbridge-source --region us-west-1

  2. Delete the Amazon EventBridge forwarding stack in the DR Region.
    aws cloudformation delete-stack --stack-name drs-eventbridge-dr --region us-east-2

  3. Delete the SSM Automation documents and the stand-down parameter.
    aws ssm delete-document --name DRS-Agent-Onboard --region us-west-1
    aws ssm delete-document --name DRS-Agent-Heal --region us-west-1
    aws ssm delete-document --name DRS-Agent-Offboard --region us-west-1
    aws ssm delete-parameter --name /drs/control/event-in-progress --region us-west-1

  4. After the other stacks are deleted, delete the IAM role stack.
    aws cloudformation delete-stack --stack-name drs-automation-iam --region us-west-1

  5. (Optional) If you created the SNS topic and S3 bucket only for this solution, delete them.

Conclusion

With a DR=yes tag in place, onboarding keeps the agent installed and registered, and healing restarts or reinstalls it when replication stalls. When you descope an instance, offboarding stops replication, removes the source server, and writes a JSON audit record to Amazon S3. That record tells you whether billing stopped or whether a partial teardown needs an operator’s follow-up. The whole lifecycle runs from one tag, without function code for your team to maintain.

The June 2023 post Deploying AWS Elastic Disaster Recovery at scale with AWS Systems Manager covered the initial install. This solution builds on it with ongoing health checks and offboarding.

Next steps

Start by cloning the repository and deploying it in audit mode in a test account. Tag a few instances with DR=yes and let onboarding run for a day. The audit reports in Amazon S3 show what the automation would install or repair on each instance, without changing anything. When the reports match what you expect, turn on installation for those instances. Then set DR=no on one of them to check the offboarding notification before you turn on teardown. If you have questions or improvements, open an issue in the GitHub repository.

Additional resources


About the authors

Manisha Yadav

Manisha Yadav

Manisha is a Delivery Consultant with AWS Professional Services in Gurugram, India. She helps enterprise customers move workloads to AWS and then keep them recoverable, mostly with AWS Elastic Disaster Recovery and AWS Systems Manager. The automation in this post started as her answer to managing Replication Agents one instance at a time.

Danish Shamim

Danish Shamim

Danish is a Senior Delivery Consultant at AWS Professional Services, where he focuses on disaster recovery and large migrations. He helps enterprise customers protect and move their workloads, and he builds the automation and runbooks that keep those solutions running in production.

Vimal Bhati

Vimal Bhati

Vimal helps AWS customers move workloads to AWS as a Delivery Consultant at AWS Professional Services. He works mostly on Infrastructure as Code with AWS CloudFormation, and he contributed the deployment tooling for this solution.

Streamlining access to powerful disaster recovery capabilities of AWS

Post Syndicated from Jennifer Moran original https://aws.amazon.com/blogs/architecture/streamlining-access-to-powerful-disaster-recovery-capabilities-of-aws/

Learn how you can use AWS services like AWS Backup and AWS Elastic Disaster Recovery (AWS DRS), along with AWS Resilience Competency Partner solutions like Arpio to implement powerful and comprehensive Disaster Recovery solutions.

Resilience is the ability of your application to keep running even when “bad stuff” happens. A critical part of your resilience strategy is Disaster Recovery (DR). DR is what protects you against less frequent, but bigger faults like natural disasters, technical faults, and bad actors. To maintain critical business continuity, disaster recovery requires recovering your workload to a new site, such as a different AWS Region or AWS account.

AWS provides powerful tools for all aspects of resilience. However, achieving a comprehensive Disaster Recovery solution for your cloud workloads using native AWS services requires planning and engineering effort. This is because, as the Shared Responsibility Model for Resiliency states, resilience is a shared responsibility between AWS and the customer. This blog post will help you understand your responsibilities and show you how to reduce the work required to access the powerful DR capabilities of AWS.

In this blog post, we take a building blocks approach. Starting with the tools like AWS Backup to protect your data, we then add protection for Amazon Elastic Compute Cloud (Amazon EC2) compute using AWS Elastic Disaster Recovery (AWS DRS). Finally, we show how to use the full capabilities of AWS to restore your entire workload—data, infrastructure, networking, and configuration, using Arpio disaster recovery automation.

Your recovery site

For DR, your recovery site is usually going to be a different AWS Region (cross-Region) or a different AWS account (cross-account) than where your workload runs.

Cross-Region backup and recovery are essential for disaster recovery. This helps to keep your workloads protected if an event causes your source Region to be unable to run your workload. AWS Regions are strong fault isolation boundaries, so the event in your source is highly unlikely to affect your recovery Region.

Cross-account backup is a critical security measure to enable recovery from malware and ransomware. By storing copies of your data in a separate clean room recovery account with distinct credentials, you create an isolated environment that can’t be accessed, even if the source account is compromised.

Protecting your data

We start with your data—your data is the foundation of your workload.

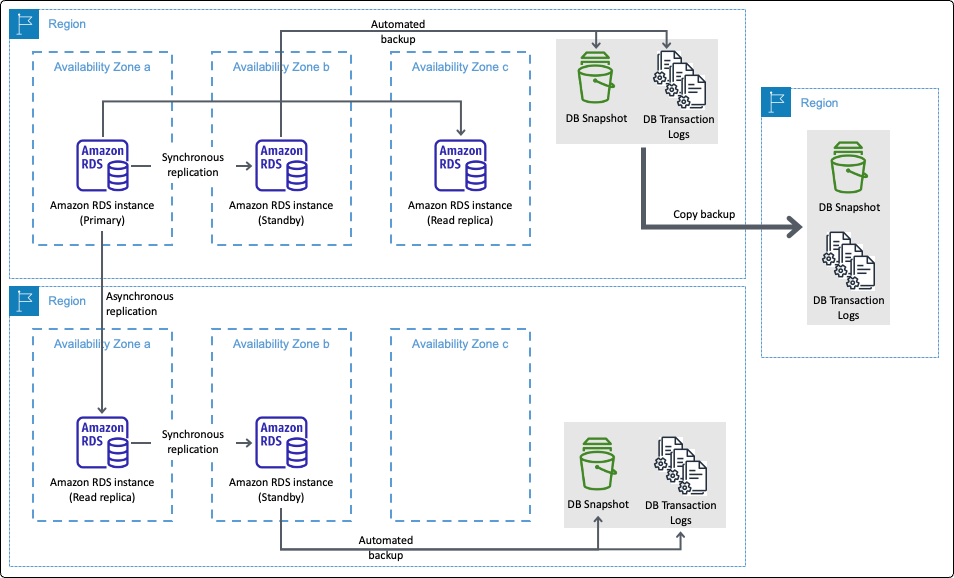
Each AWS data storage resource offers the ability to back up or replicate your data. For example, Amazon Elastic Block Store (Amazon EBS) snapshots, Amazon Relational Database Service (Amazon RDS) for Db2) Backups, and Amazon Simple Storage Service (Amazon S3) replication, offer data protection for Amazon EBS volumes, Amazon RDS Databases instances, and Amazon S3 Buckets respectively. Figure 1, for example, illustrates the several methods and destinations of backup and replication for Amazon RDS.

AWS Backup and replication for Amazon RDS

Figure 1. AWS Backup and replication for Amazon RDS

AWS Backup takes this further, tying together many of these disparate backup technologies, giving a single plane of glass to configure data backup plans across resources. AWS Backup also added backup capabilities for AWS resources that previously didn’t have them such as Amazon Elastic File System (Amazon EFS) and Amazon FSx. It also provides the ability to back up your data to a different AWS Region or AWS account. It even enabled cross-Region backup for services like Amazon DynamoDB, which previously didn’t have that capability.

AWS Backup is a powerful tool for protecting your data. With your data protected, you will then need additional automation to get to a fully recovered workload. If you want to build this yourself, AWS offers the tools to do this. In this prior blog post on Backup and Restore, we go more into detail about adding automation using Amazon EventBridge and AWS Lambda functions for automated recovery. For more information, see figures 6 and 7.

With its ability to create vaults for secure storage, define policies for governance, and set schedules for automation, AWS Backup centralizes and streamlines the backup process. Instead of managing backups service by service, you can enforce consistent protection across resources, reduce manual effort, and streamline recovery when it matters most.

Protecting your Amazon EC2 compute

As important as data is, only restoring your data isn’t a complete solution to recovering from disaster. You must also restore your compute resources.

For static Amazon EC2 instances, you can create snapshots of your instances as Amazon Machine Images (AMIs), or use AWS Backup to manage this for you. By static instances, we mean those you create directly and maintain, as opposed to those created by Amazon EC2 Auto Scaling. Such a strategy can deliver a Recovery Points Objective (RPO) and Recovery Time Objective (RTO) of minutes to hours. The size (and growth in size) of your EC2 instances determines the time to back them up. Their size and launch time determines the time to restore them.

If you need real-time RPO (near-zero data loss) and RTO (recovery) in minutes or less, then AWS DRS is the solution here. AWS DRS provides a nearly continuous block-level replication, recovery orchestration, and automated server conversion capabilities. With these, you to achieve a crash-consistent recovery point objective of seconds, and a recovery time objective typically ranging between 5–20 minutes. You can also use AWS DRS to configure your recovery Amazon Virtual Private Cloud (Amazon VPC). So, with the right settings, you can get your EC2 networking to look like your primary environment.

Protecting everything in your entire workload

Restoring data and static EC2 instances is only part of the disaster recovery solution that you need. Modern workloads often rely on a broader range of compute services, including EC2 Auto Scaling, AWS Lambda, Amazon ECS, and Amazon Elastic Kubernetes Service (Amazon EKS). For ECS and EKS, you can run on EC2 instances or go serverless with AWS Fargate. You will need a solution that can restore either of these.

The challenge with these services is making sure that they are recreated with the right configuration and metadata. For example, EC2 instance types and volume sizes, EC2 user data, or AWS Lambda function code, and not everything here is stateless. Both ECS and EKS can rely on persistent Amazon EBS volumes or Amazon Elastic File System (Amazon EFS). In those cases, recovery requires restoring the data and reattaching volumes restored from backup to the correct ECS tasks or EKS pods.

You can build automation to do all of this, or you can rely on an AWS Resilience Software Competency Partner solution to take care of this for you. Arpio is a software as a service (SaaS) product focused on discovering and backing up everything it takes to run your workload on AWS, and recovering it cross-Region and cross-account as a fully functional workload.

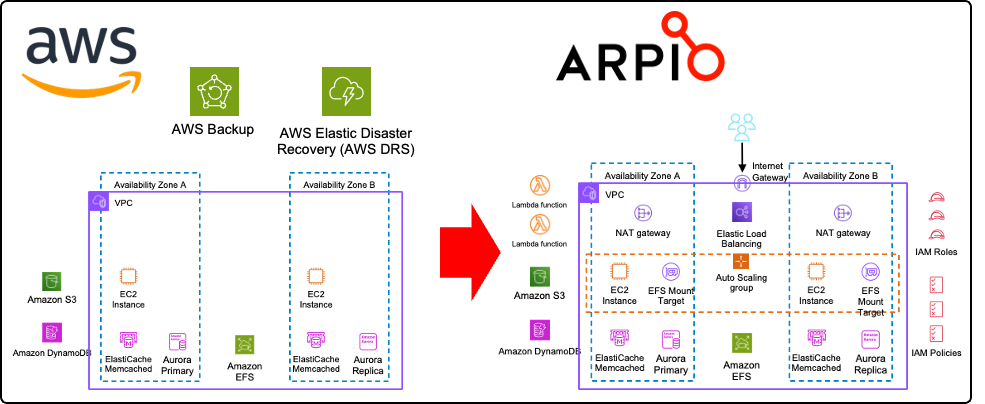
Figure 2 illustrates how AWS tools (left) establish a powerful foundation for robust workload recovery. Beyond these foundational building blocks, full recovery requires additional resources (right), including AWS compute options as discussed. Furthermore, complex networking (potentially spanning VPCs and accounts), infrastructure, and IAM principals are critical. Arpio uses and extends AWS Backup, AWS DRS, and other AWS service capabilities to back up and restore a functional AWS workload, including all its necessary components. This unburdens you from the undifferentiated heavy lifting of building your own automation. You still have responsibilities in the shared responsibility model, but Arpio takes on most of the work of getting you backed up and recovered.

AWS tools on the left provide a powerful foundation for full recovery on the right

Figure 2. AWS tools on the left provide a powerful foundation for full recovery on the right

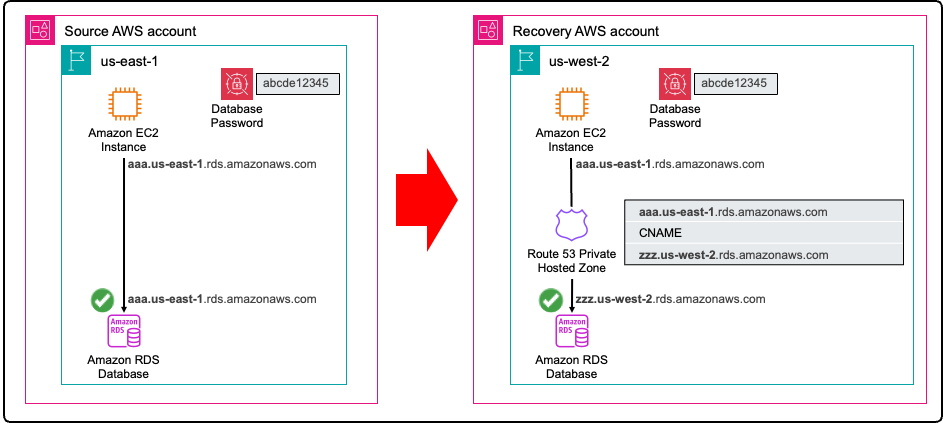
Even with data, compute, networking, infrastructure, and IAM principals restored, there is another requirement to achieve full recovery: translation of your configuration. For example, an application that accesses the Amazon RDS database requires configuration information about the DB endpoint and credentials. When restoring your RDS instance into your recovery environment, it will have a new endpoint. Arpio addresses this using a two-fold strategy. First Arpio will find all references to the early database endpoint name and translate them to the new database endpoint name. Next, Arpio will also create an Amazon Route 53 private hosted zone in the recovered VPC, mapping the early endpoint to the new one using a CNAME record. This way, applications still using the early name still connect to the newly recovered database. Arpio also securely backs up the credentials in your recovery account, for every database backup taken, ready to be recovered for the point in time that you recover your database from. Figure 3 shows how your recovered application can seamlessly access your restored database.

Arpio automation ensures your applications can access your restored database in the recovery environment

Figure 3. Arpio automation ensures your applications can access your restored database in the recovery environment

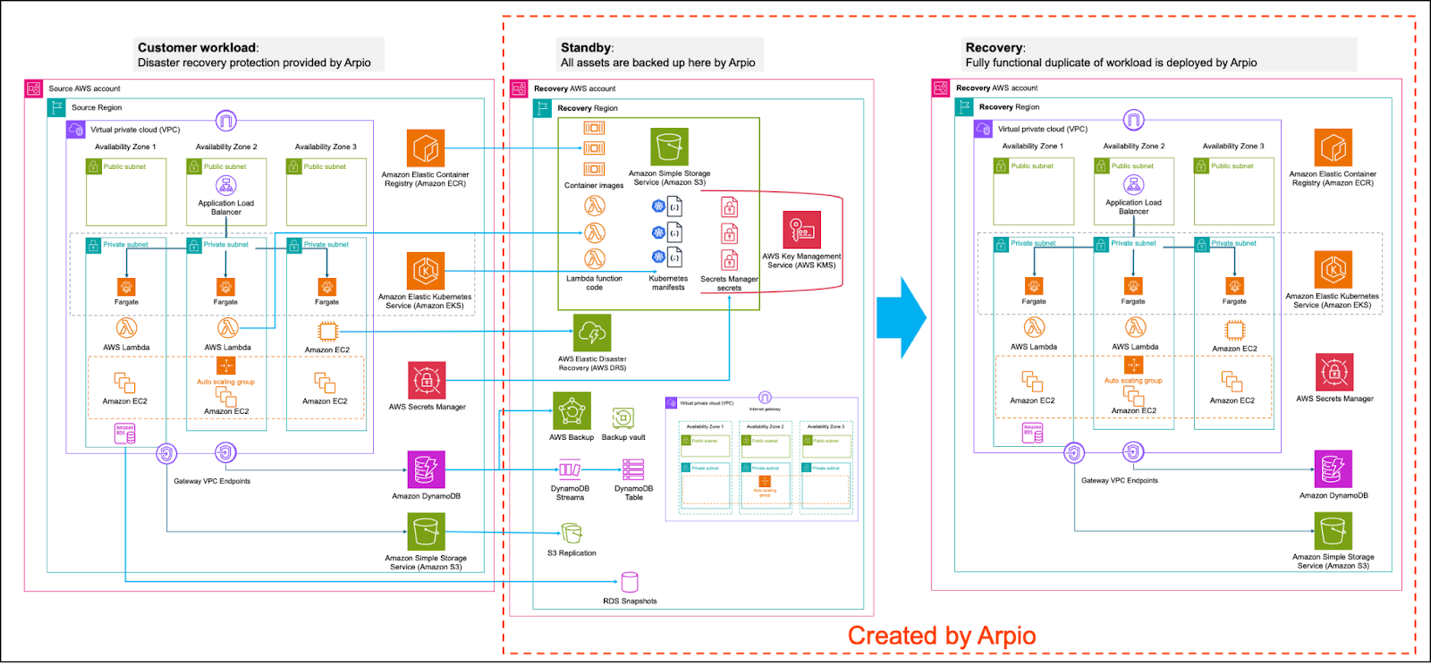
Figure 4 shows a sample AWS workload protected by Arpio. In the standby state, you can see how Arpio is coordinating multiple AWS services. When a disaster or ransomware event occurs, you can launch a recovery. This will create a fully recovered workload as seen in the recovery stage on the right.

Sample AWS workload protected by Arpio

Figure 4. Sample AWS workload protected by Arpio

Arpio does all of this in your accounts, on your behalf. To enable this, Arpio applies AWS Well-Architected Tool (AWS WA Tool) best practices for security, using only IAM roles with least-privilege permissions. For example, the IAM role used to access your source AWS account is incapable of changing or mutating your source workload and is explicitly denied from reading or exfiltrating any data.

With its ability to back up over 140 AWS resources and restore them as fully functioning AWS workloads in a cross-Region cross-account recovery environment, Arpio builds on top of the powerful AWS tooling to streamline your complete workload recovery.

Conclusion

Disaster recovery (DR) is essential for a robust resilience strategy. By using the powerful tools offered by AWS and complementing them with AWS Resilience Competency Partner solutions like Arpio, organizations can significantly streamline access to comprehensive and powerful disaster recovery capabilities for their AWS workloads.


About the authors

Architecting for Disaster Recovery on AWS Outposts Racks with AWS Elastic Disaster Recovery

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/architecting-for-disaster-recovery-on-aws-outposts-racks-with-aws-elastic-disaster-recovery/

This blog post is written by Brianna Rosentrater, Hybrid Edge Specialist SA.

AWS Elastic Disaster Recovery Service (AWS DRS) now supports disaster recovery (DR) architectures that include on-premises Windows and Linux workloads running on AWS Outposts. AWS DRS minimizes downtime and data loss with fast, reliable recovery of on-premises and cloud-based applications using affordable storage, minimal compute, and point-in-time recovery. Both services are billed and managed from your AWS Management Console.

Like workloads running in AWS Regions, it’s critical to plan for failures. Outposts are designed with resiliency in mind, providing redundant power, networking, and are available to order with N+M active compute instance capacity. In other words, for every physical N compute servers, you have the option of including M redundant hosts capable of handling the workload during a failure. When leveraging AWS DRS with Outpost, you can plan for larger-scale failure modes, such as data center outages, by replicating mission-critical workloads to other remote data center locations or the AWS Region.

In this post, you’ll learn how AWS DRS can be used with Outpost rack to architect for high availability in the event of a site failure. The post will examine several different architectures enabled by AWS DRS that provide DR for Outpost, and the benefits of each method described.

Prerequisites

Each of these architectures described below need the following:

Public internet access isn’t needed, AWS PrivateLink and AWS Direct Connect are supported for replication and failback which is a significant security benefit.

Planning for failure

Disasters come in many forms and are often unplanned and unexpected events. Regardless of whether your workload resides on premises, in a colocation facility, or in an AWS Region, it’s critical to define the Recovery Time Objective (RTO) and Recovery Point Objective (RPO) which are often workload-specific. These two metrics profile how long a service can be down during recovery and quantify the acceptable amount of data loss. RTO and RPO guide you in choosing the appropriate strategy such as backup and recovery, pilot light, warm standby, or a multi-site (active-active) approach.

With AWS DRS, while failing back to a test machine (not the original source server), replication of the source server continues. This allows failback drills without impacting RPO, and non-disruptive failback drills are an important part of disaster planning to validate your recovery plan meets your expected RPO/RTO as per your business requirements.

How AWS DRS integrates with Outpost

AWS DRS uses an AWS Replication Agent at the source to capture the workload and transfer it to a lightweight staging area, which resides on an Outpost equipped with Amazon S3 on Outposts. This method also provides the ability to perform low-effort, non-disruptive DR drills before making the final cutover. The AWS Replication Agent doesn’t need a reboot nor does it impact your applications during installation.

When an Outpost’s subnet is selected as the target for replication or launch, all associated AWS DRS components remain within the Outpost, including the AWS DRS server conversion technology. These conversion servers convert source disks of servers being migrated so that they can boot and run in the target infrastructure, Amazon EBS volumes, snapshots, and replication servers. The replication servers replicate the disks to the target infrastructure. With AWS DRS you can control the data replication path using private connectivity options such as a virtual private network (VPN), AWS Direct Connect, VPC peering, or another private connection. Learn more about using a private IP for data replication.

AWS DRS provides nearly continuous replication for mission-critical workloads and supports deployment patterns including on-premises to Outpost, Outpost to Region, Region to Outpost, and between two logical Outposts through local networks. To leverage Outpost with AWS DRS, simply select the Outpost subnet as your target or source for replication when configuring AWS DRS for your workload. If you are currently using CloudEndure DR for disaster recovery with Outpost, see these detailed instructions for migrating to AWS DRS from CloudEndure DR.

DR from on-premises to Outpost

Outpost can be used as a DR target for on-premises workloads. By deploying an Outpost in a remote data center or colocation a significant distance from the source within the same geo-political boundary, you can replicate workloads across great distances and increase resiliency of the data while ensuring adherence to data residency policies or legislation.

DR from on-premises to Outposts

Figure 1 – DR from on-premises to Outposts

In Figure 1, on premises sources replicate traffic from a LAN to a staging area residing in an Outpost subnet via the local gateway. This allows workloads to failover from their on-premises environment to an Outpost in a different physical location during a disaster.

The staging areas and replication servers run on Amazon Elastic Compute Cloud (Amazon EC2) with Amazon EBS volumes and require Amazon S3 on Outposts where the Amazon EBS snapshots reside.

The replication agent is responsible for providing nearly continuous, block-level replication from your LAN using TCP/1500 with traffic routing to Amazon EC2 instances using the Outposts local gateway.

DR from Outpost to Region

Since its initial release, Outpost has supported Amazon EBS snapshots written to Amazon S3 located in the AWS Region. Backup to an AWS Region is one of the most cost-effective and easiest-to-configure DR approaches, enabling data redundancy outside of your Outpost and data center.

This method also offers flexibility for restoration within an AWS Region if the original deployment is irrecoverable. However, depending on the frequency of the snapshots and the timing of the failure, backup, and recovery to the Region has the potential to have an RPO/RTO spanning hours depending on the throughput of the service link.

For critical workloads, AWS DRS can reduce RTO to minutes and RPO in the sub-second range. After creating an initial replication of workloads that reside on the Outpost, AWS DRS provides nearly continuous, block-level replication in the Region. Just like replication from non-AWS virtual machines or bare metal servers, AWS DRS resources, including Replication Servers, Conversion Servers, Amazon EBS Volumes, and Snapshots reside in the Region.

DR from Outpost to Region

Figure 2 – DR from Outpost to Region

In Figure 2, data replication is performed over the service link from Amazon EC2 instances running locally on an Outpost to an AWS Region. The service link traverses either public Region connectivity or AWS Direct Connect.

AWS Direct Connect is the recommended option because it provides low latency and consistent bandwidth for the service link back to a Region, which also improves the reliability of transmission for AWS DRS replication traffic.

The service link is comprised of redundant, encrypted VPN tunnels. Replication traffic can also be sent privately without traversing the public internet by leveraging Private Virtual Interfaces with Direct Connect for the service link.

With this architecture in place, you can mitigate disasters and reduce downtime by failing over to the AWS Region using AWS DRS.

DR from Region to Outpost

AWS provides multiple Availability Zones (AZs) within a Region and isolated AWS Regions globally for the greatest possible fault tolerance and stability. The reliability pillar of AWS’s Well-Architected Framework encourages distributing workloads across AZs and replicating data between Regions when the need for distances exceeds those of AZs.

AWS DRS supports nearly continuous replication of workloads from a Region to an Outpost within your data center or colocation facility for DR. This deployment model provides increased durability from a source AWS Region to an Outpost anchored to a different Region.

In this model, AWS DRS components remain on-premises within the Outpost, but data charges are applicable as data egresses from the Region back to the data center and Amazon S3 on Outposts is required on the destination Outpost.

DR from Region to Outpost

Figure 3 – DR from Region to Outpost

Implementing the preceding architecture diagram enables failover of critical workloads from the Region to on-premises Outposts seamlessly. Keep in mind that AWS Regions provide the management and control plane for Outpost, making it critical to consider probability and frequency of service link interruptions as a part of your DR planning. Scenarios such as warm standby with pre-allocated Amazon EC2 and Amazon EBS resources may prove more resilient during service link disruptions.

DR between two Outposts

Each logical Outpost is comprised of one or more physical racks. Logical Outposts are in independent colocations of one another, and support deployments in disparate data centers or colocation facilities. You can elect to have multiple logical Outposts anchored to different Availability Zones or Regions. AWS DRS unlocks options for replication between two logical Outposts, leading to increased resiliency and reducing the impact of your data center as a single point of failure. In the following architecture, nearly continuous replication captured from a single Outpost source is applied at a second logical Outpost.

DR between two Outposts

Figure 4 – DR between two Outposts

Supporting both directional and bidirectional replication between Outposts can minimize disruption caused by events that take down a data center, Availability Zone, or even the entire Region result in minimal disruption. In the following architecture diagram, bidirectional data replication occurs between the Outposts by routing traffic via the local gateways, minimizing outbound data charges from the Region and allowing for more direct routing between deployment sites that could potentially span significant distances. AWS DRS cannot communicate with resources directly utilizing a customer-owned IP address pool (CoIP pool).
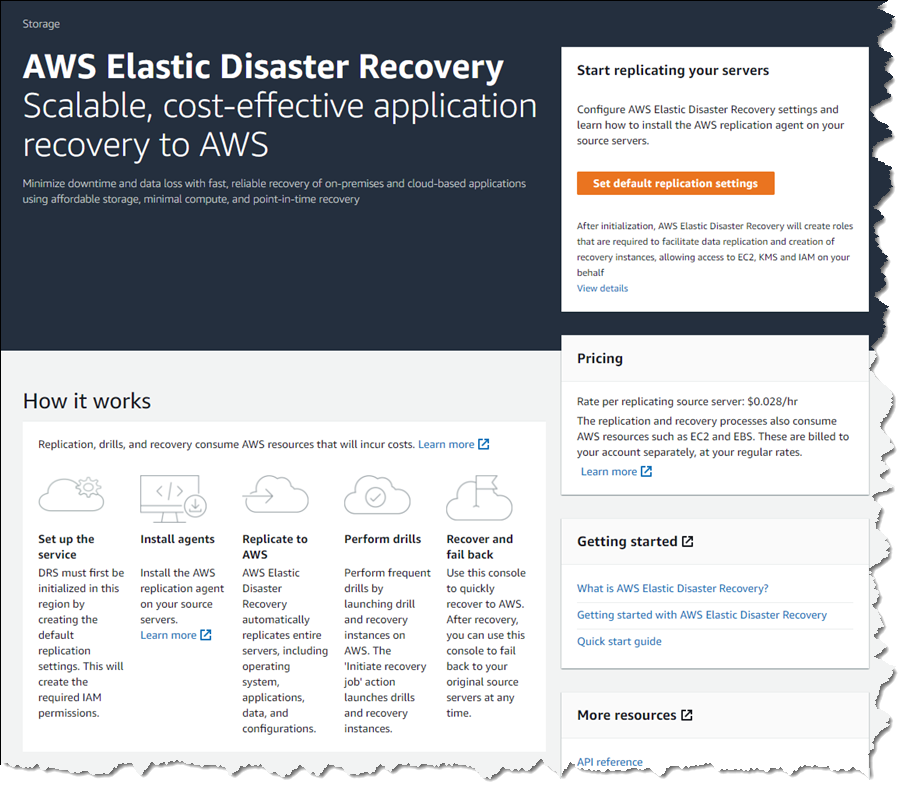
Figure 5 – DR between two Outposts – bidirectional 

Architecture Considerations

When planning an Outpost deployment leveraging AWS DRS, it’s critical to consider the impact on storage. As a general best practice, AWS recommends planning for a 2:1 ratio consisting of EBS volumes used for nearly continuous replication and Amazon EBS snapshots on Amazon S3 for point-in-time recovery. While it’s unlikely that all servers would need recovery simultaneously, it’s also important to allocate a reserve of EBS volume capacity, which will launch at the time of recovery. Amazon S3 on Outpost is needed for each Outpost used as a replication destination, and the recommendation is to plan for a 1:1 ratio consisting of S3 on Outposts storage, plus the rate of data change. For example, if your data change rate is 10%, you’d want to plan for 110% S3 on Outpost use with AWS DRS.

Amazon CloudWatch has integrated metrics for EC2, Amazon EBS, and Amazon S3 capacity on Outposts, making it easy to create custom tailored dashboards and integrate with Simple Notification Service (Amazon SNS) for alerts at defined thresholds. Monitoring these metrics is critical in making sure that proper free space is available for data replication to occur unimpeded. CloudWatch has metrics available for AWS DRS as well. You can also use the AWS DRS service page in the AWS Console to monitor the status of your recovery instances.

Consider taking advantage of Recovery Plans within AWS DRS to make sure that related services are recovered in a particular order. For example, during a disaster, it might be critical to first bring up a database before recovering application tiers. Recovery plans provide the ability to group related services and apply wait times to individual targets.

Conclusion

AWS Outpost enables low latency, data residency, or data gravity-constrained workloads by supplying managed cloud compute and storage services within your data center or colocation. When coupled with AWS DRS, you can decrease RPO and RTO through a variety of flexible deployment models with sources and destinations ranging from on-premises, the Region, or another AWS Outpost.

The most visited AWS DevOps blogs in 2022

Post Syndicated from original https://aws.amazon.com/blogs/devops/the-most-visited-aws-devops-blogs-in-2022/

As we kick off 2023, I wanted to take a moment to highlight the top posts from 2022. Without further ado, here are the top 10 AWS DevOps Blog posts of 2022.

#1: Integrating with GitHub Actions – CI/CD pipeline to deploy a Web App to Amazon EC2

Coming in at #1, Mahesh Biradar, Solutions Architect and Suresh Moolya, Cloud Application Architect use GitHub Actions and AWS CodeDeploy to deploy a sample application to Amazon Elastic Compute Cloud (Amazon EC2).

Architecture diagram from the original post.

#2: Deploy and Manage GitLab Runners on Amazon EC2

Sylvia Qi, Senior DevOps Architect, and Sebastian Carreras, Senior Cloud Application Architect, guide us through utilizing infrastructure as code (IaC) to automate GitLab Runner deployment on Amazon EC2.

Architecture diagram from the original post.

#3 Multi-Region Terraform Deployments with AWS CodePipeline using Terraform Built CI/CD

Lerna Ekmekcioglu, Senior Solutions Architect, and Jack Iu, Global Solutions Architect, demonstrate best practices for multi-Region deployments using HashiCorp Terraform, AWS CodeBuild, and AWS CodePipeline.

Architecture diagram from the original post.

#4 Use the AWS Toolkit for Azure DevOps to automate your deployments to AWS

Mahmoud Abid, Senior Customer Delivery Architect, leverages the AWS Toolkit for Azure DevOps to deploy AWS CloudFormation stacks.

Architecture diagram from the original post.

#5 Deploy and manage OpenAPI/Swagger RESTful APIs with the AWS Cloud Development Kit

Luke Popplewell, Solutions Architect, demonstrates using AWS Cloud Development Kit (AWS CDK) to build and deploy Amazon API Gateway resources using the OpenAPI specification.

Architecture diagram from the original post.

#6: How to unit test and deploy AWS Glue jobs using AWS CodePipeline

Praveen Kumar Jeyarajan, Senior DevOps Consultant, and Vaidyanathan Ganesa Sankaran, Sr Modernization Architect, discuss unit testing Python-based AWS Glue Jobs in AWS CodePipeline.

Architecture diagram from the original post.

#7: Jenkins high availability and disaster recovery on AWS

James Bland, APN Global Tech Lead for DevOps, and Welly Siauw, Sr. Partner solutions architect, discuss the challenges of architecting Jenkins for scale and high availability (HA).

Architecture diagram from the original post.

#8: Monitor AWS resources created by Terraform in Amazon DevOps Guru using tfdevops

Harish Vaswani, Senior Cloud Application Architect, and Rafael Ramos, Solutions Architect, explain how you can configure and use tfdevops to easily enable Amazon DevOps Guru for your existing AWS resources created by Terraform.

Architecture diagram from the original post.

#9: Manage application security and compliance with the AWS Cloud Development Kit and cdk-nag

Arun Donti, Senior Software Engineer with Twitch, demonstrates how to integrate cdk-nag into an AWS Cloud Development Kit (AWS CDK) application to provide continual feedback and help align your applications with best practices.

Featured image from the original post.

#10: Smithy Server and Client Generator for TypeScript (Developer Preview)

Adam Thomas, Senior Software Development Engineer, demonstrate how you can use Smithy to define services and SDKs and deploy them to AWS Lambda using a generated client.

Architecture diagram from the original post.

A big thank you to all our readers! Your feedback and collaboration are appreciated and help us produce better content.


About the author:

Brian Beach

Brian Beach has over 20 years of experience as a Developer and Architect. He is currently a Principal Solutions Architect at Amazon Web Services. He holds a Computer Engineering degree from NYU Poly and an MBA from Rutgers Business School. He is the author of “Pro PowerShell for Amazon Web Services” from Apress. He is a regular author and has spoken at numerous events. Brian lives in North Carolina with his wife and three kids.

Automated in-AWS Failback for AWS Elastic Disaster Recovery

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/automated-in-aws-failback-for-aws-elastic-disaster-recovery/

I first covered AWS Elastic Disaster Recovery (DRS) in a 2021 blog post. In that post, I described how DRS “enables customers to use AWS as an elastic recovery site for their on-premises applications without needing to invest in on-premises DR infrastructure that lies idle until needed. Once enabled, DRS maintains a constant replication posture for your operating systems, applications, and databases.” I’m happy to announce that, today, DRS now also supports in-AWS failback, adding to the existing support for non-disruptive recovery drills and on-premises failback included in the original release.

I also wrote in my earlier post that drills are an important part of disaster recovery since, if you don’t test, you simply won’t know for sure that your disaster recovery solution will work properly when you need it to. However, customers rarely like to test because it’s a time-consuming activity and also disruptive. Automation and simplification encourage frequent drills, even at scale, enabling you to be better prepared for disaster, and now you can use them irrespective of whether your applications are on-premises or in AWS. Non-disruptive recovery drills provide confidence that you will meet your recovery time objectives (RTOs) and recovery point objectives (RPOs) should you ever need to initiate a recovery or failback. More information on RTOs and RPOs, and why they’re important to define, can be found in the recovery objectives documentation.

The new automated support provides a simplified and expedited experience to fail back Amazon Elastic Compute Cloud (Amazon EC2) instances to the original Region, and both failover and failback processes (for on-premises or in-AWS recovery) can be conveniently started from the AWS Management Console. Also, for customers that want to customize the granular steps that make up a recovery workflow, DRS provides three new APIs, linked at the bottom of this post.

Failover vs. Failback
Failover is switching the running application to another Availability Zone, or even a different Region, should outages or issues occur that threaten the availability of the application. Failback is the process of returning the application to the original on-premises location or Region. For failovers to another Availability Zone, customers who are agnostic to the zone may continue running the application in its new zone indefinitely if so required. In this case, they will reverse the recovery replication, so the recovered instance is protected for future recovery. However, if the failover was to a different Region, its likely customers will want to eventually fail back and return to the original Region when the issues that caused failover have been resolved.

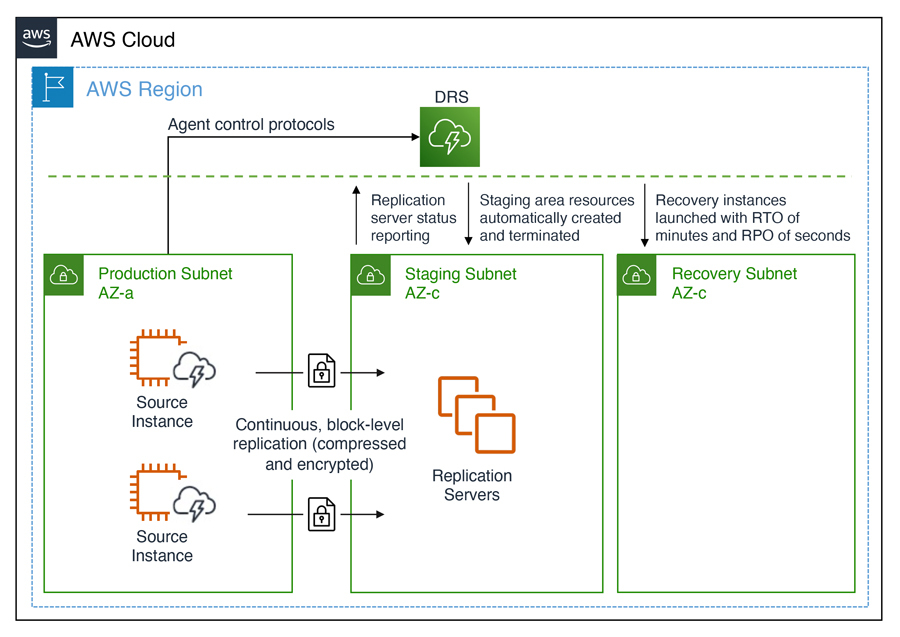
The below images illustrate architectures for in-AWS applications protected by DRS. The architecture in the image below is for cross-Availability Zone scenarios.

Cross-Availability Zone architecture for DRS

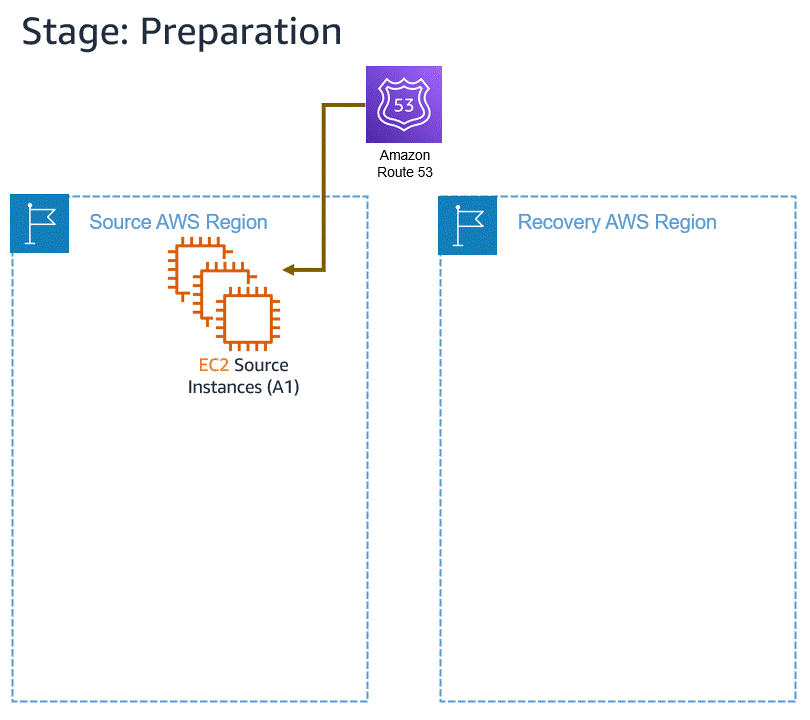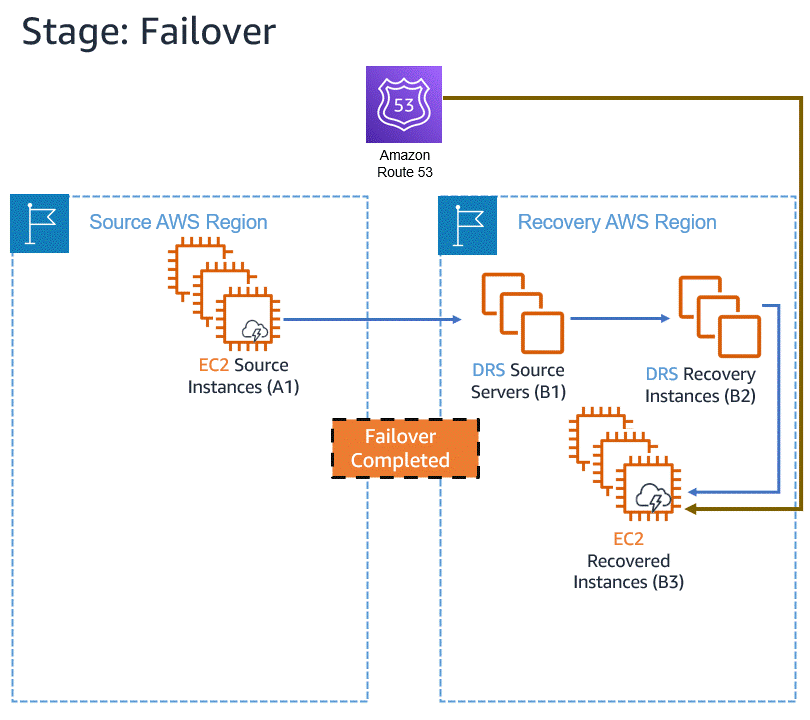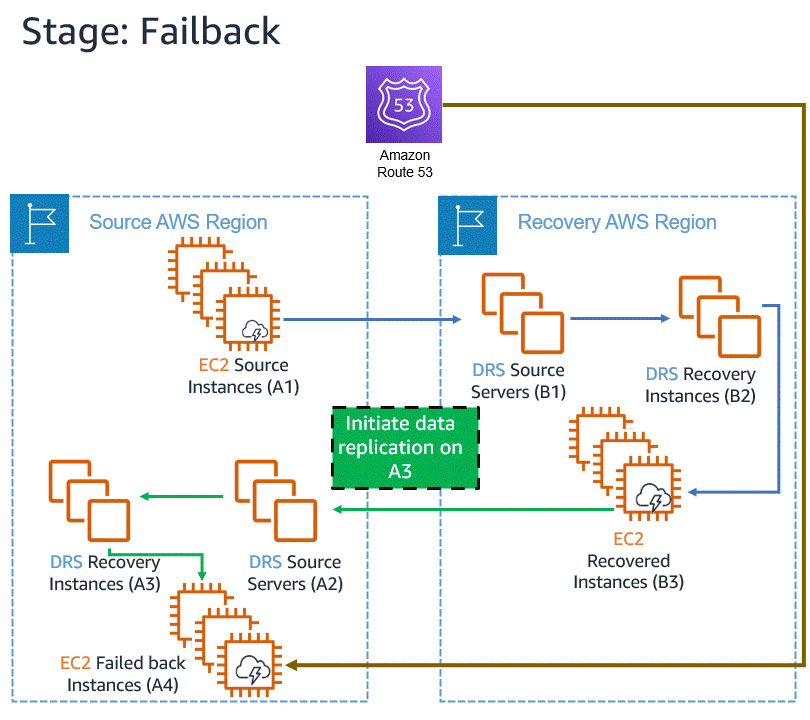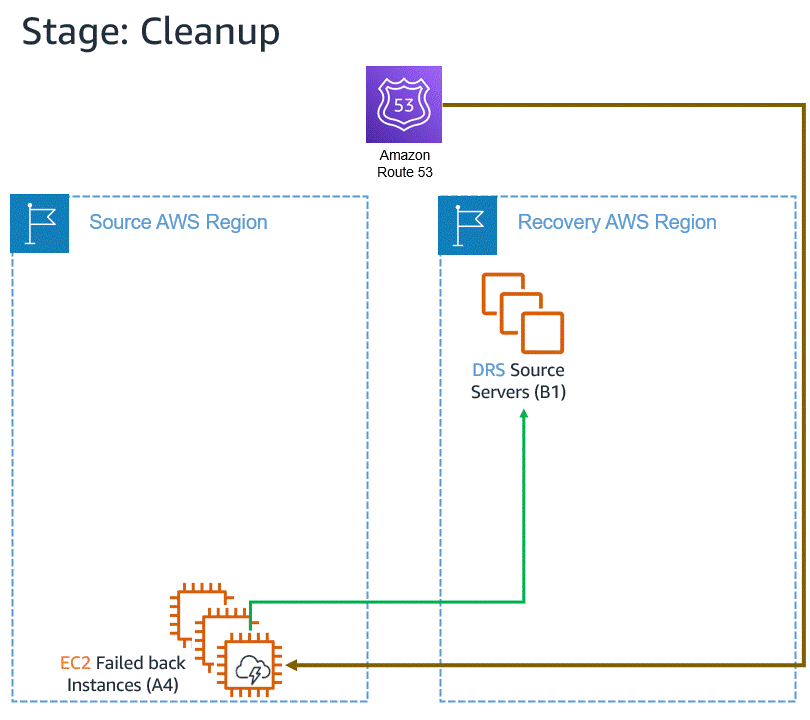
The architecture diagram below is for cross-Region scenarios.

Cross-Region architecture for DRS

Let’s assume an incident occurs with an in-AWS application, so we initiate a failover to another AWS Region. When the issue has been resolved, we want to fail back to the original Region. The following animation illustrates the failover and failback processes.

Illustration of the failover and failback processes

Learn more about in-AWS failback with Elastic Disaster Recovery
As I mentioned earlier, three new APIs are also available for customers who want to customize the granular steps involved. The documentation for these can be found using the links below.

The new in-AWS failback support is available in all Regions where AWS Elastic Disaster Recovery is available. Learn more about AWS Elastic Disaster Recovery in the User Guide. For specific information on the new failback support I recommend consulting this topic in the service User Guide. 

— Steve

AWS MGN Update – Configure DR, Convert CentOS Linux to Rocky Linux, and Convert SUSE Linux Subscription

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/aws-mgn-update-configure-dr-convert-centos-linux-to-rocky-linux-and-convert-suse-linux-subscription/

Just about a year ago, Channy showed you How to Use the New AWS Application Migration Server for Lift-and-Shift Migrations. In his post, he introduced AWS Application Migration Service (AWS MGN) and said:

With AWS MGN, you can minimize time-intensive, error-prone manual processes by automatically replicating entire servers and converting your source servers from physical, virtual, or cloud infrastructure to run natively on AWS. The service simplifies your migration by enabling you to use the same automated process for a wide range of applications.

Since launch, we have added agentless replication along with support for Windows 10 and multiple versions of Windows Server (2003, 2008, and 2022). We also expanded into additional regions throughout 2021.

New Post-Launch Actions
As the title of Channy’s post stated, AWS MGN initially supported direct, lift-and-shift migrations. In other words, the selected disk volumes on the source servers were directly copied, bit-for-bit to EBS volumes attached to freshly launched Amazon Elastic Compute Cloud (Amazon EC2) instances.

Today we are adding a set of optional post-launch actions that provide additional support for your migration and modernization efforts. The actions are initiated and managed by the AWS Systems Manager agent, which can be automatically installed as the first post-launch action. We are launching with an initial set of four actions, and plan to add more over time:

Install Agent – This action installs the AWS Systems Manager agent, and is a prerequisite to the other actions.

Disaster Recovery – Installs the AWS Elastic Disaster Recovery Service agent on each server and configures replication to a specified target region.

CentOS Conversion – If the source server is running CentOS, the instances can be migrated to Rocky Linux.

SUSE Subscription Conversion – If the source service is running SUSE Linux via a subscription provided by SUSE, the instance is changed to use an AWS-provided SUSE subscription.

Using Post-Launch Actions
My AWS account has a post-launch settings template that serves as a starting point, and provides the default settings each time I add a new source server. I can use the values from the template as-is, or I can customize them as needed. I open the Application Migration Service Console and click Settings to view and edit my template:

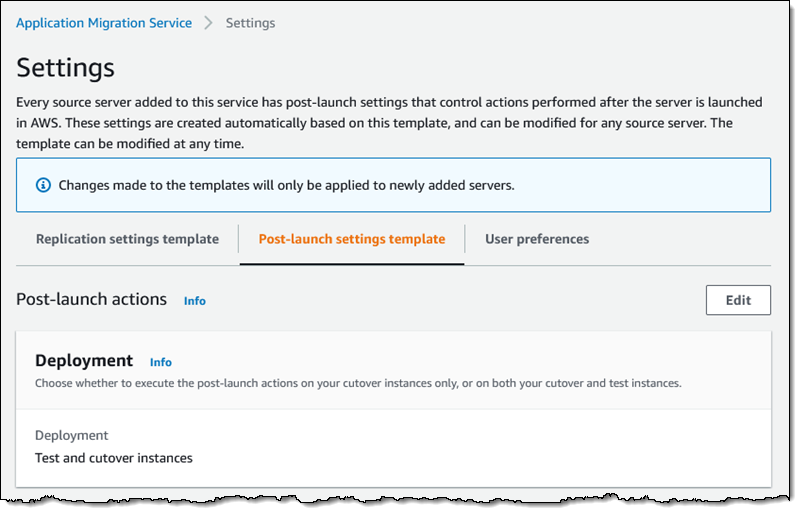
I click Post-launch settings template, and review the default values. Then I click Edit to make changes:

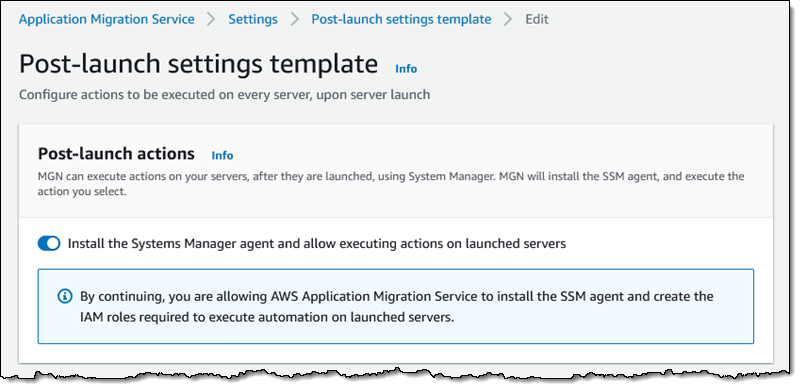
As I noted earlier, the Systems Manager agent executes the other post-launch actions, and is a prerequisite, so I enable it:

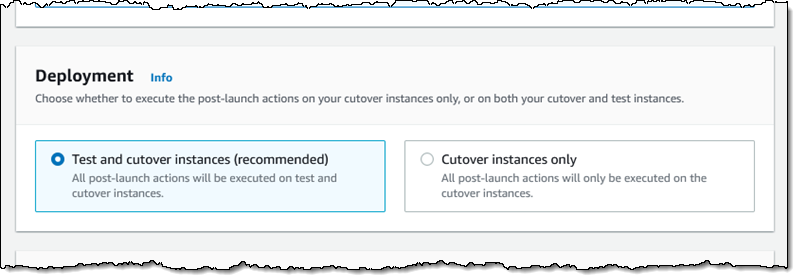
Next, I choose to run the post-launch actions on both my test and cutover instances, since I want to test against the final migrated configuration:

I can now configure any or all of the post-launch options, starting with disaster recovery. I check Configure disaster recovery on migrated servers and choose a target region:

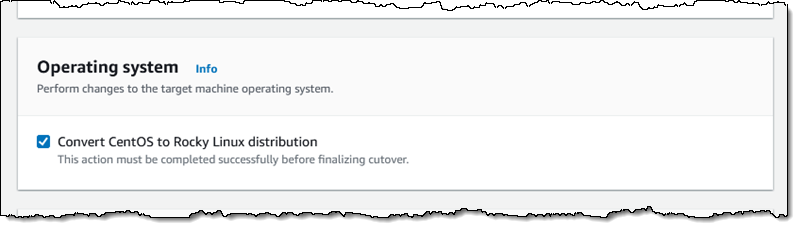
Next, I check Convert CentOS to Rocky Linux distribution. This action converts a CentOS 8 distribution to a Rocky Linux 8 distribution:

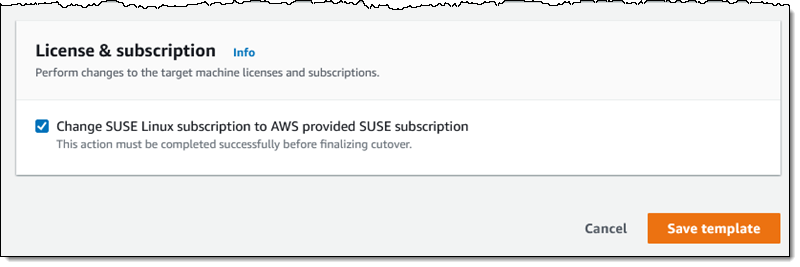
Moving right along, I check Change SUSE Linux Subscription to AWS provided SUSE Linux subscription, and then click Save template:

To learn more about pricing for the SUSE subscriptions, visit the Amazon EC2 On-Demand Pricing page.

After I have set up my template, I can view and edit the settings for each of my source servers. I simply select the server and choose Edit post-launch settings from the Replication menu:

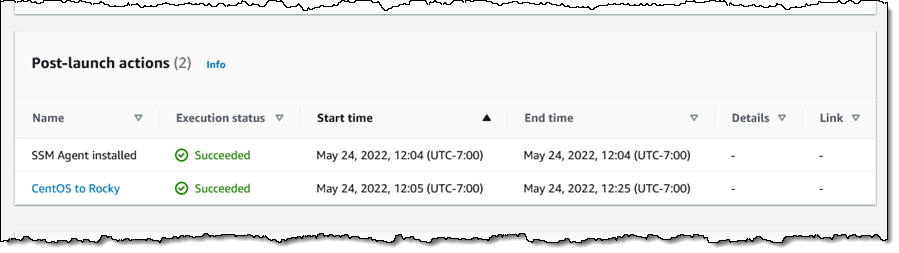
The post-launch actions will be run at the appropriate time on the test or the cutover instances, per my selections. Any errors that arise during the execution of an action are written to the SSM execution log. I can also examine the Migration dashboard for each source server and review the Post-launch actions:

Available Now
The post-launch actions are available now and you can start using them today in all regions where AWS Application Migration Service (AWS MGN) is supported.

— Jeff;

Migration updates announced at re:Invent 2021

Post Syndicated from Angélica Ortega original https://aws.amazon.com/blogs/architecture/migration-updates-announced-at-reinvent-2021/

re:Invent is a yearly event that offers learning and networking opportunities for the global cloud computing community. 2021 marks the launch of several new features in different areas of cloud services and migration.

In this blog, we’ll cover some of the most important recent announcements.

AWS Mainframe Modernization (Preview)

Mainframe modernization has become a necessity for many companies. One of the main drivers fueling this requirement is the need for agility, as the market constantly demands new functionalities. The mainframe platform, due to its complex dependencies, long procurement cycles, and escalating costs, makes it impossible for companies to innovate at the needed pace.

Mainframe modernization can be a complex undertaking. To assist you, we have launched a comprehensive platform, called AWS Mainframe Modernization, that enables two popular migration patterns: replatforming, and automated refactoring.

AWS Mainframe Modernization flow

Figure 1. AWS Mainframe Modernization flow

AWS Migration and Modernization Competency

Application modernization is becoming an important migration strategy, especially for strategic business applications. It brings many benefits: software licensing and operation cost optimization, better performance, agility, resilience, and more. Selecting a partner with the required expertise can help reduce the time and risk for these kinds of projects. In the next section, you’ll find a summary of the experience required by a partner to get the AWS Migration and Modernization Competency. More information can be found at AWS Migration Competency Partners.
AWS Application Migration Service (AWS MGN)

AWS MGN is recommended as the primary migration service for lift and shift migrations. Customers currently using AWS Server Migration Service are encouraged to switch to it for future migrations.

Starting in November 2021, AWS MGN supports agentless replication from VMWare vCenter versions 6.7 and 7.0 to the AWS Cloud. This new feature is intended for users who want to rehost their applications to AWS, but cannot install the AWS Replication Agent on individual servers due to company policies or technical restrictions.

AWS Elastic Disaster Recovery

Two of the pillars of the Well-Architected Framework are Operational Excellence and Reliability. Both are directly concerned with the capability of a service to recover and work efficiently. AWS Elastic Disaster Recovery is a new service to help you to minimize downtime and data loss with fast, reliable, and recovery of on-premises and cloud-based applications. It uses storage, compute, point-in-time recovery, and cost-optimization.

AWS Resilience Hub

AWS Resilience Hub is a service designed to help customers define, measure, and manage the resilience of their applications in the cloud. This service helps you define RTO (Recovery Time Objective) and RPO (Recovery Point Objective) and evaluates the configuration to meet the requirements defined. Aligned with the AWS Well-Architected Framework, this service can recover applications deployed with AWS CloudFormation, and integrates with AWS Fault Injection Simulator, AWS Systems Manager, or Amazon CloudWatch.

AWS Migration Hub Strategy Recommendations

One of the critical tasks in a migration is determining the right strategy. AWS Migration Hub can help you build a migration and modernization strategy for applications running on-premises or in AWS. AWS Migration Hub Strategy Recommendations were announced on October 2021. It’s designed to be the starting point for your cloud journey. It helps you to assess the appropriate strategy to transform your portfolios to use the full benefits of cloud services.

AWS Migration Hub Refactor Spaces (Preview)

Refactoring is the migration strategy that requires the biggest effort, but it permits you to take full advantage of cloud-native features to improve agility, performance, and scalability. AWS Migration Hub Refactor Spaces is the starting point for incremental application refactoring to microservices in AWS. It will help you reduce the undifferentiated heavy lifting of building and operating your AWS infrastructure for incremental refactoring.

AWS Database Migration Service

AWS Database Migration Service (AWS DMS) is a service that helps you migrate databases to AWS quickly and securely.

AWS DMS Fleet Advisor is a new free feature of AWS DMS that enables you to quickly build a database and analytics migration plan, by automating the discovery and analysis of your fleet. AWS DMS Fleet Advisor is intended for users looking to migrate a large number of database and analytic servers to AWS.

AWS Microservice Extractor for .NET is a new free tool and simplifies the process of re-architecting applications into smaller code projects. Modernize and transform your .NET applications with an assistive tool that analyzes source code and runtime metrics. It creates a visual representation of your application and its dependencies.

This tool visualizes your applications source code, helps with code refactoring, and assists in extraction of the code base into separate code projects.  Teams can then develop, build, and operate independently to improve agility, uptime, and scalability.

AWS Migration Evaluator

AWS Migration Evaluator (ME) is a migration assessment service that helps you create a directional business case for AWS Cloud planning and migration. Building a business case for the cloud can be a time-consuming process on your own. With Migration Evaluator, organizations can accelerate their evaluation and decision-making for migration to AWS. During 2021, there were some existing improvements to mention:

  • Quick Insights. This new capability of Migration Evaluator, provides customers with a one-page summary of their projected AWS costs, based on measured on-premises provisioning and utilization.
  • Enhanced Microsoft SQL Discovery. This is a new feature of the Migration Evaluator Collector, which assists you by including your SQL Server environment in their migration assessment.
  • Agentless Collection for Dependency Mapping. The ME Collector now enables agentless network traffic collection to be sent to the customer’s AWS Migration Hub account.

AWS Amplify Studio

This is a visual development environment that offers frontend developers new features to accelerate UI development with minimal coding, while integrating with Amplify. Read Introducing AWS Amplify Studio.

Conclusion

Migration is a crucial process for many enterprises as they move from on-premises systems to the cloud. It helps accelerate your cloud journey, and offers additional tools and methodologies created by AWS. AWS has created and is continually improving services and features to optimize the migration process and help you reach your business goals faster.

Related information

Scalable, Cost-Effective Disaster Recovery in the Cloud

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/scalable-cost-effective-disaster-recovery-in-the-cloud/

Should disaster strike, business continuity can require more than just periodic data backups. A full recovery that meets the business’s recovery time objectives (RTOs) must also include the infrastructure, operating systems, applications, and configurations used to process their data. The growing threats of ransomware highlight the need to be able to perform a full point-in-time recovery. For businesses affected by a ransomware attack, restoration of data from an old, possibly manual, backup will not be sufficient.

Previously, businesses have elected to provision separate, physical disaster recovery (DR) infrastructure. However, customers tell us this can be both space- and cost-prohibitive, involving capital expenditure on hardware and facilities that remain idle until called upon. The infrastructure also incurs overhead in terms of regular inspection and maintenance, typically manual, to ensure that should it ever be called upon, it’s ready and able to handle the current business load, which may have grown considerably since initial provisioning. This also makes testing difficult and expensive.

Today, I am happy to announce AWS Elastic Disaster Recovery (DRS) a fully scalable, cost-effective disaster recovery service for physical, virtual, and cloud servers, based on CloudEndure Disaster Recovery. DRS enables customers to use AWS as an elastic recovery site without needing to invest in on-premises DR infrastructure that lies idle until needed. Once enabled, DRS maintains a constant replication posture for your operating systems, applications, and databases. This helps businesses meet recovery point objectives (RPOs) of seconds, and RTOs of minutes, after disaster strikes. In cases of ransomware attacks, for example, DRS also allows recovery to a previous point in time.

DRS provides for recovery that scales as needed to match your current setup and does not need any time-consuming manual processes to maintain that readiness. It also offers the ability to perform disaster recovery readiness drills. Just as it’s important to test restoration of data from backups, being able to conduct recovery drills in a cost-effective manner without impacting ongoing replication or user activities can help give confidence that you can meet your objectives and customer expectations should you need to call on a recovery.

AWS Elastic Disaster Recovery console home

Elastic Disaster Recovery in Action
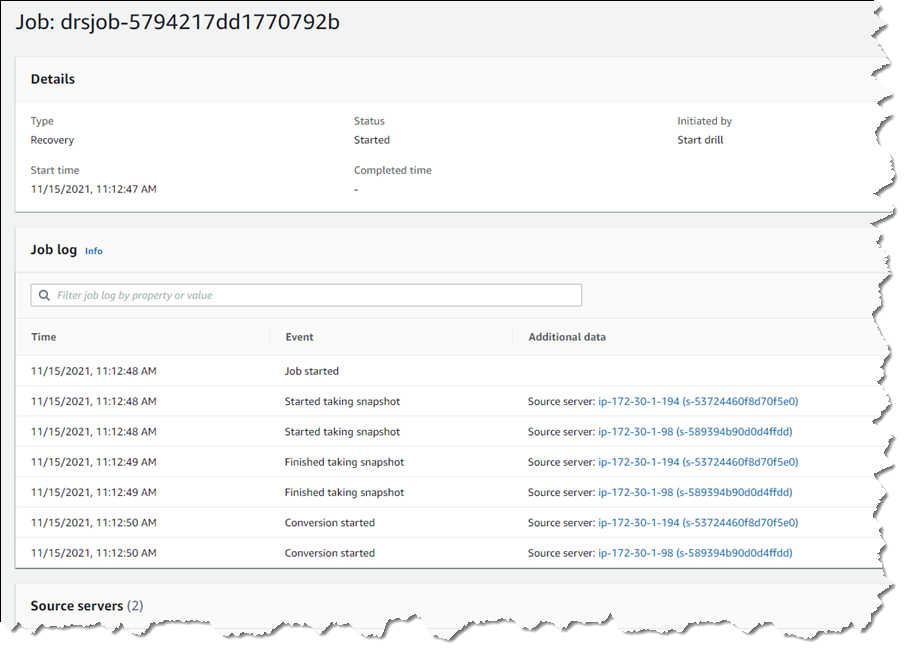
Once enabled, DRS continuously replicates block storage volumes from physical, virtual, or cloud-based servers, allowing it to support business RPOs measured in seconds. Recovery includes applications running on physical infrastructure, VMware vSphere, Microsoft Hyper-V, and cloud infrastructure to AWS. You’re able to recover all your applications and databases that run on supported Windows and Linux operating systems, with DRS orchestrating the recovery process for your servers on AWS to support an RTO measured in minutes.

Using an agent that you install on your servers, DRS securely replicates the data to a staging area subnet in a selected Region in your AWS account. The staging area subnet reduces costs to you, using affordable storage and minimal compute resources. Within the DRS console, you can recover Amazon Elastic Compute Cloud (Amazon EC2) instances in a different AWS Region if required. With DRS automating replication and recovery procedures, you can set up, test, and operate your disaster recovery capability using a single process without the need for specialized skill sets.

DRS gives you the flexibility to pay on an hourly basis, instead of needing to commit to a long-term contract or a set number of servers, a benefit over on-premises or data center recovery solutions. DRS charges hourly, on a pay-as-you-go basis. You can find specific details on pricing at the product page.

Exploring Elastic Disaster Recovery
To set up disaster recovery for my resources I first need to configure my default replication settings. As I mentioned earlier, DRS can be used with physical, virtual, and cloud servers. For this post, I’m going to use a collection of EC2 instances as my source servers for disaster recovery.

From the DRS console home, shown earlier, choosing Set default replication settings takes me to a short initialization wizard. In the wizard, I first need to select an Amazon Virtual Private Cloud (VPC) subnet that will be used for staging. This subnet does not need to be in the same VPC as my resources, but I need to select one that is not private or blocked to the world. Below, I’ve chosen a subnet from my default VPC in my Region. I can also change the instance type used for the replication instance. I chose to keep the suggested default and clicked Next to proceed.

Choosing the staging area subnet and replication instance type for DRS

I also left the default settings unchanged for the next two pages. In Volumes and security groups, the wizard suggests I use the general-purpose SSD (gp3) Amazon Elastic Block Store (EBS) storage type and to use a security group provided by DRS. On the Additional settings page I can elect to use a private IP for data replication instead of routing over the public internet, and set the snapshot retention period, which defaults to seven days. Clicking Next one final time, I arrive at the Review and create page of the wizard. Choosing Create default completes the process of configuring my default replication settings.

Finalizing default replication settings for DRS

With my replication settings finalized (I can edit them later if I wish, from the Actions menu on the Source servers console page) it’s time to set up my servers. I’m running a test fleet in EC2 that includes two Windows Server 2019 instances, and three Amazon Linux 2 instances. The DRS User Guide contains full instructions on how to obtain and set up the agent on each server type, so I won’t repeat them here. As I run and configure the agent on each of my server instances, the Source servers list automatically updates to include the new source server. The status of the initial sync, and future replication and recovery status of each source server, are summarized in this view.

Replication sync activity on servers

Selecting a hostname entry in the list takes me to a detail page. Here I can view a recovery dashboard, information on the underlying server, disk settings (including the ability to change the staging disk type from the default gp3 type selected by the initialization wizard, or whatever you choose during setup), and launch settings, shown below, that govern the recovery instance that will be created if I choose to initiate a drill or an actual recovery job.

DRS launch settings for a recovery server

Just like data backups, where established best practice is to periodically verify that the backups can actually be used to restore data, we recommend a similar best practice for disaster recovery. So, with my servers all configured and fully replicated, I decided to start a drill for a point-in-time (PIT) recovery for two of my servers. On these instances, following initial replication, I’d installed some additional software. In my scenario, perhaps this installation had gone badly wrong, or I’d fallen victim to a ransomware attack. Either way, I wanted to know and be confident that I could recover my servers if and when needed.

In the Source servers list I selected the two servers that I’d modified and from the Initiate recovery job drop-down menu, chose Initiate drill. Next, I can choose the recovery PIT I’m interested in. This view defaults to Any, meaning it lists all recovery PIT snapshots for the servers I selected. Or, I can choose to filter to All, meaning only PIT snapshots that apply to all the selected servers will be listed. Selecting All, I chose a time just after I’d completed installing additional software on the instances, and clicked Initiate drill.

Selecting a recovery point-in-time for multiple servers

I’m returned to the Source servers list, which shows status as the recovery proceeds. However, I switched to the Recovery job history view for more detail.

In-progress recovery drill

Clicking the job ID, I can drill down further to view a detail page of the source servers involved in the recovery (and can drill down further for each), as well as an overall recovery job log.

Viewing the recovery job log

Note – during a drill, or an actual recovery, if you go to the EC2 console you’ll notice one or more additional instances, started by DRS, running in your account (in addition to the replication server). These temporary instances, named AWS Elastic Disaster Recovery Conversion Server, are used to process the PIT snapshots onto the actual recovery instance(s) and will be terminated when the job is complete.

Once the recovery is complete, I can see two new instances in my EC2 environment. These are in the state matching the point-in-time recovery I selected, and are using the instance types I selected earlier in the DRS initialization wizard. I can now connect to them to verify that the recovery drill performed as expected before terminating them. Had this been a real recovery, I would have the option of terminating the original instances to replace them with the recovery versions, or handle whatever other tasks are needed to complete the disaster recovery for my business.

New instances matching my point-in-time recovery selection

Set Up Your Disaster Recovery Environment Today
AWS Elastic Disaster Recovery is generally available now in the US East (N. Virginia), US East (Ohio), US West (Oregon), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Europe (Frankfurt), Europe (Ireland), and Europe (London) Regions. Review the AWS Elastic Disaster Recovery User Guide for more details on setup and operation, and get started today with DRS to eliminate idle recovery site resources, enjoy pay-as-you-go billing, and simplify your deployments to improve your disaster recovery objectives.

— Steve