Tag Archives: AWS Organizations

Quantum-resistant signing on AWS, Part 1: Build a software supply chain with ML-DSA

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/security/quantum-resistant-signing-on-aws-part-1-build-a-software-supply-chain-with-ml-dsa/

Software supply chain attacks have grown in both frequency and sophistication. Recent high-profile compromises of build systems and open source dependencies demonstrate that attackers increasingly target the trust mechanisms that verify software integrity. Those trust mechanisms rely on digital signature algorithms, and today many use traditional algorithms such as Rivest-Shamir-Adleman (RSA) and the Elliptic Curve Digital Signature Algorithm (ECDSA). If a sufficiently powerful quantum computer could forge these signatures, an attacker could potentially inject unauthorized code into signed artifacts, fabricate build attestations, or impersonate legitimate publishers. Using quantum-resistant signatures today defends against threats that might emerge in the future.

Since 2025, the Commercial National Security Algorithm Suite 2.0 (CNSA 2.0), published by the US National Security Agency (NSA), has required US National Security Systems (NSS) to “support and prefer” quantum-resistant signatures for software and firmware, with exclusive use mandated by 2030. The EU Cyber Resilience Act (CRA) takes full effect in December 2027. It requires manufacturers to maintain verifiable software integrity throughout a product’s lifecycle. Organizations that ship software to US federal agencies or sell products in the European market face converging deadlines that demand action now.

Amazon Web Services (AWS) provides the building blocks to construct a quantum-resistant software supply chain today using production-ready, generally available services. In this post, I show you how to combine Module-Lattice-Based Digital Signature Algorithm (ML-DSA) keys in AWS Key Management Service (AWS KMS), ML-DSA certificate hierarchies in AWS Private Certificate Authority, and ML-DSA trust anchors in AWS Identity and Access Management (IAM) Roles Anywhere into an end-to-end signing architecture for binaries, container images, and software bills of materials (SBOMs).

This post is Part 1 of a two-part series on adopting ML-DSA signatures, standardized in NIST FIPS 204 (ML-DSA) signatures, on AWS. As of Oct 2026, this series is the first end-to-end guide from any cloud provider for post-quantum signing across the software supply chain, from establishing an ML-DSA root of trust to enforcing algorithm policy across an organization. This part is for builders and walks through constructing and operating the signing pipeline. Part 2, Enforce your ML-DSA algorithm policy with SCPs and IAM, is for security and governance teams and shows how to turn the algorithm choices made here into preventive and detective controls across an organization.

Understanding the harvest now, forge later threat

After a cryptographically relevant quantum computer (CRQC) exists, the mathematical problems protecting today’s public-key cryptography can be solved efficiently. Attacks that are impractical today because of the computational complexity suddenly become practical using a CRQC. Most discussions of post-quantum cryptography (PQC) focus on the harvest now, decrypt later threat to data confidentiality. The asymmetric keys protecting data in transit can be efficiently derived using a CRQC, exposing the data that was meant to be protected. Digital signatures rely on the same asymmetric mathematical problems that a CRQC would break. This means that software supply chains face a parallel threat that targets integrity rather than confidentiality. An attacker who records signed artifacts today can forge those signatures in the future on a totally different artifact, using a CRQC.

Consider firmware signed with ECDSA P-256 and deployed to a fleet of embedded devices in 2026. These devices verify the firmware signature on every boot for their 15-year operational lifetime and can’t be recalled to re-sign after deployment. If a CRQC becomes operational in 2035, an attacker could produce a valid-looking signature over tampered firmware, and every device in the fleet would accept it as authentic on next restart. For organizations that rely on classical digital signatures as the primary mechanism for verifying software integrity, this weakens a critical link in the verification chain. This is why CNSA 2.0 specifies aggressive timelines for digital signatures: the artifacts you sign today must remain trustworthy for their full operational lifetime.

ML-DSA is designed to resist attacks from both classical and quantum computers. AWS KMS, AWS Private CA, and AWS IAM Roles Anywhere all support ML-DSA, making it possible to address the forge-later threat across your supply chain today without additional tooling.

Architecture overview: Five pillars of a quantum-resistant supply chain

The architecture comprises five trust pillars that together protect your software delivery pipeline:

  1. ML-DSA key management in AWS KMS – All signing keys are generated and protected in FIPS 140-3 Security Level 3 hardware security modules (HSMs). Private keys never leave the HSM boundary.
  2. ML-DSA public key infrastructure (PKI) through AWS Private CA – A certificate hierarchy (root CA, subordinate CA, end-entity certificates) binds ML-DSA public keys to identities, establishing who signed what. CA private keys are generated and stored in hardware-protected HSMs managed by the service and never leave the HSM boundary.
  3. Quantum-resistant workload identity (for external build agents) – For continuous integration and delivery (CI/CD) agents running outside AWS that authenticate through X.509 certificates, IAM Roles Anywhere with ML-DSA certificates ties the signer’s identity back to the same quantum-resistant root of trust.
  4. ML-DSA artifact signing – Build outputs (binaries, container image manifests, packages) are signed using AWS KMS ML-DSA keys. Signatures are stored alongside artifacts in Amazon Simple Storage Service (Amazon S3) or Amazon Elastic Container Registry (Amazon ECR).
  5. ML-DSA SBOM integrity attestation – The SBOM for each release is wrapped in an in-toto Statement that names the artifact it describes by digest, and the Statement is signed with the same ML-DSA code-signing key. This provides quantum-resistant proof that the dependency manifest hasn’t been tampered with and that it belongs to the artifact it accompanies.

These pillars create a chain of trust: AWS Private CA protects the root CA key in its own HSMs, issues certificates that bind identities to AWS KMS code-signing keys, IAM Roles Anywhere uses those certificates to authenticate build agents, and authenticated agents sign every artifact and SBOM they produce.
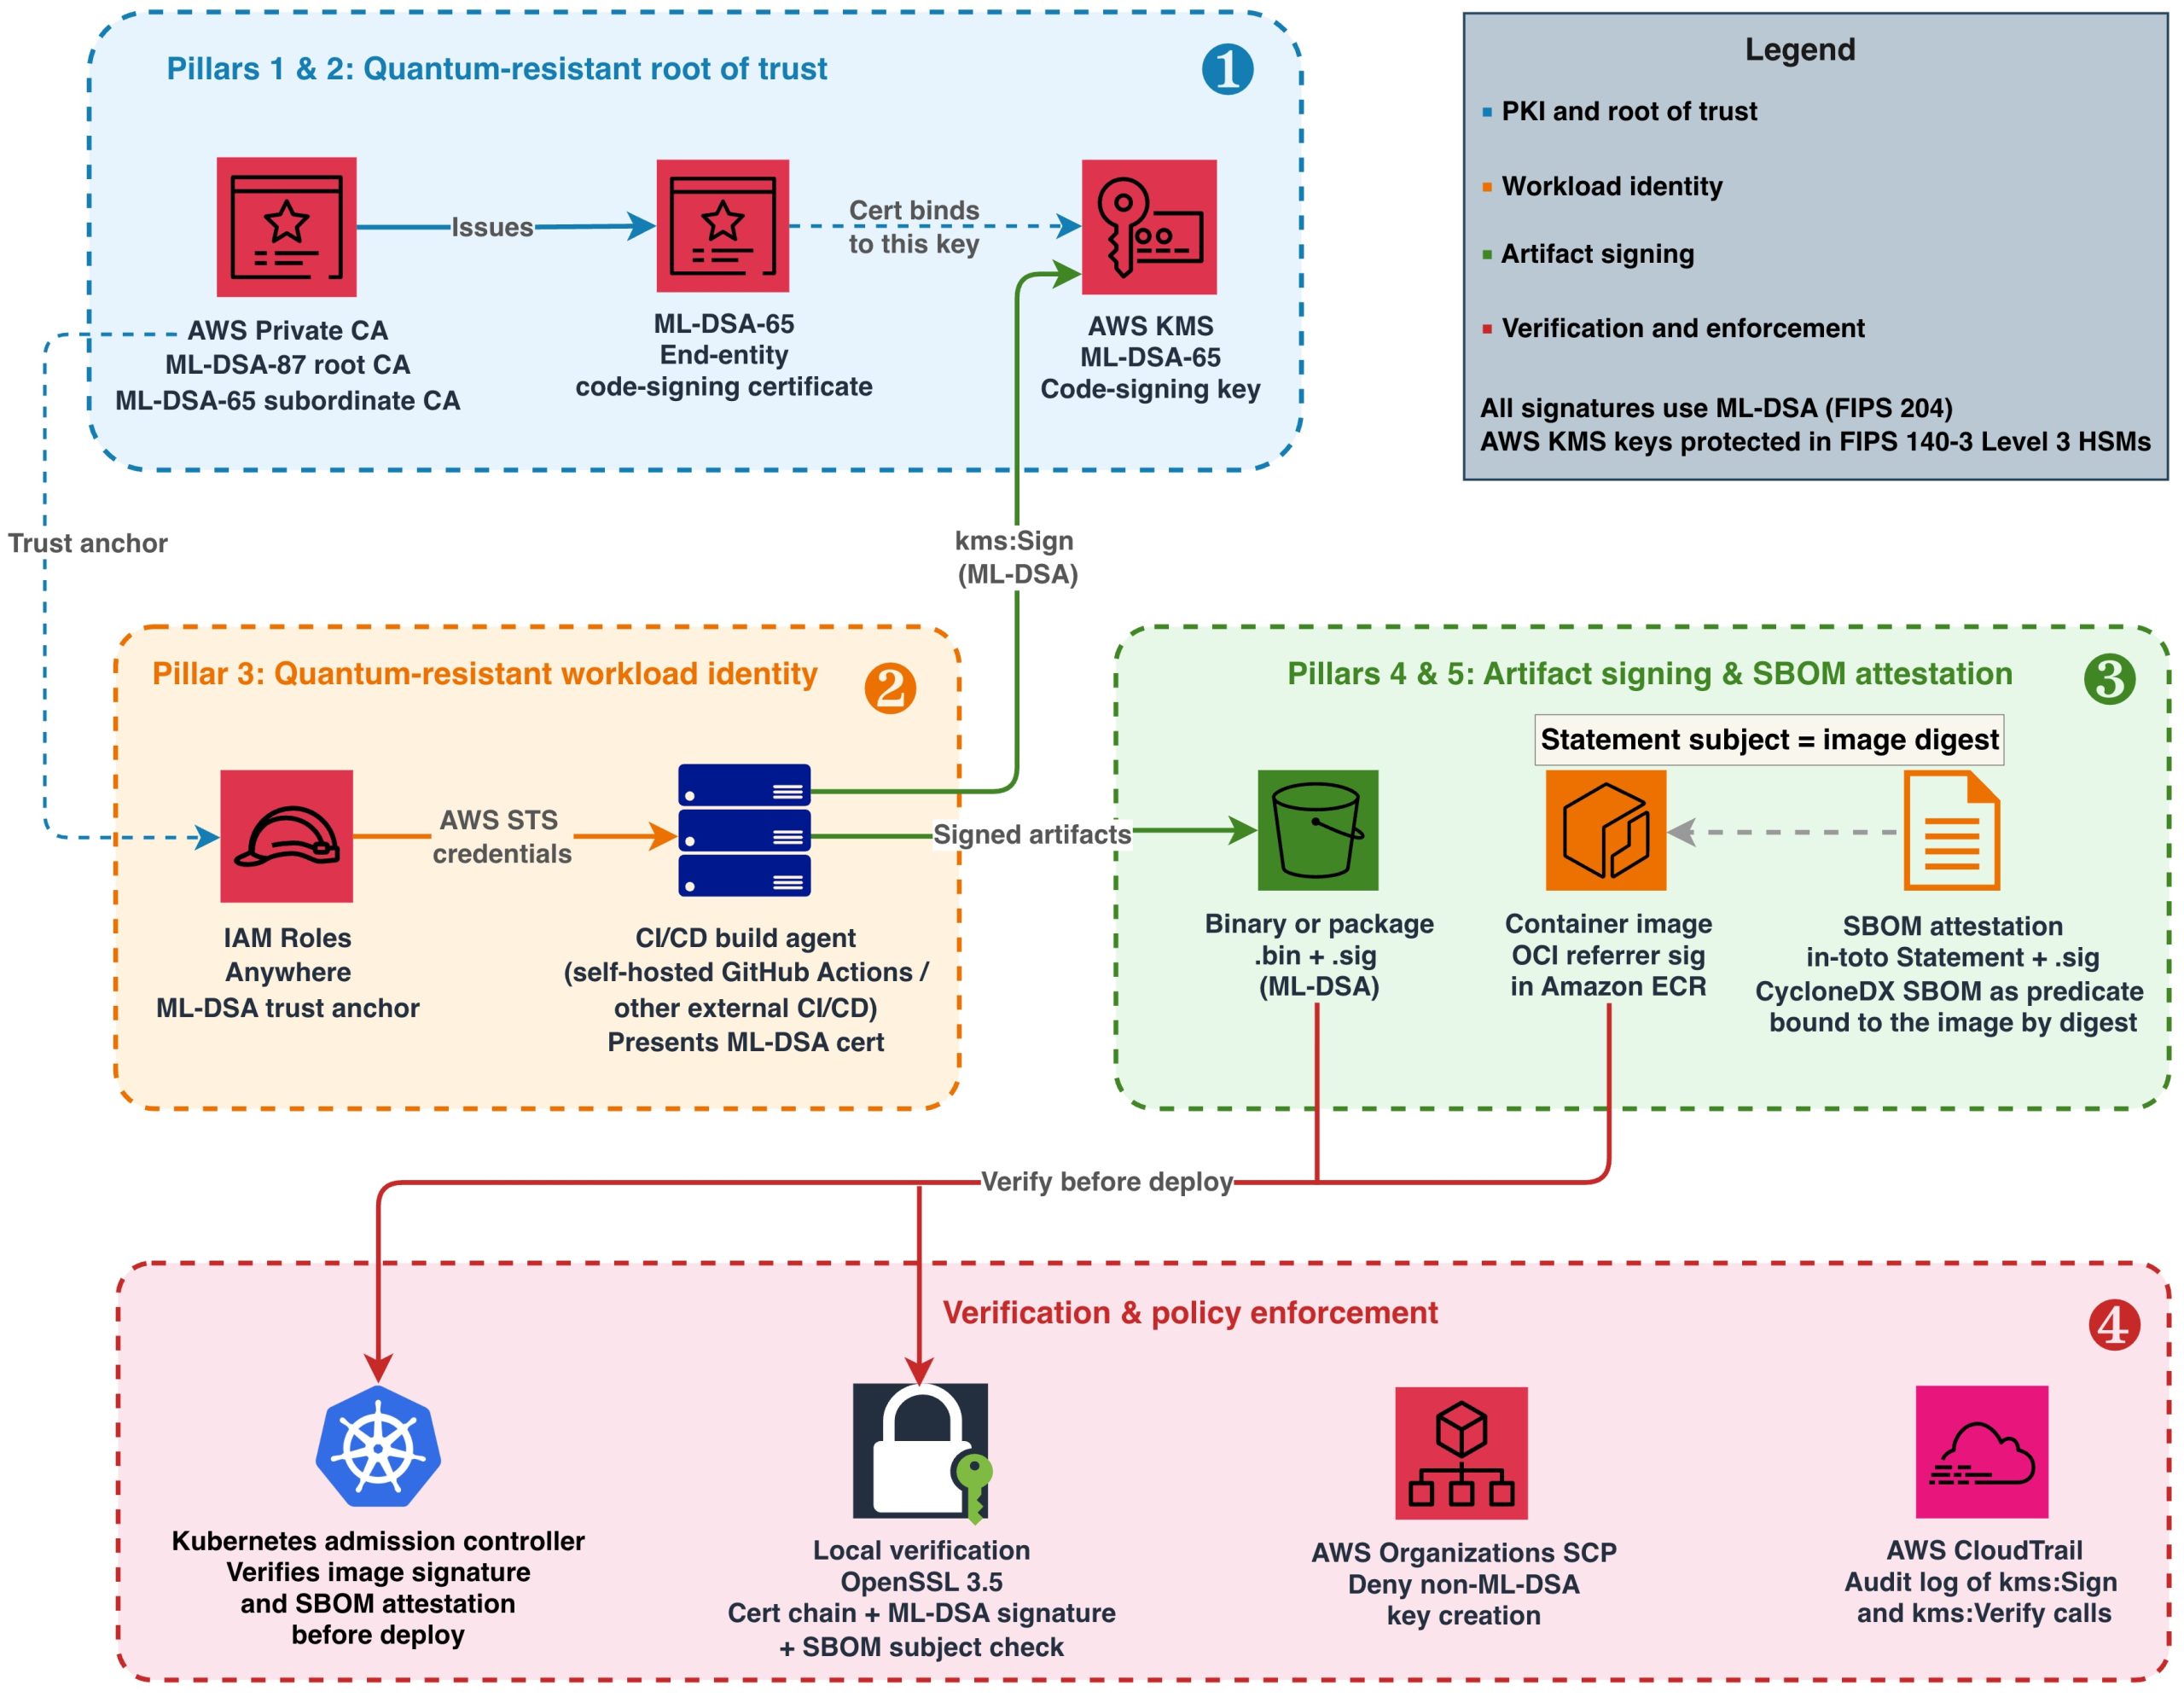
Figure 1: End-to-end quantum-resistant software supply chain on AWS

Figure 1: End-to-end quantum-resistant software supply chain on AWS

Figure 1 illustrates this architecture in four layers, numbered in the order you build them:

  1. Root of trust (Pillars 1 and 2) – Establish your AWS Private CA hierarchy and create your code-signing key in AWS KMS.
  2. Workload identity (Pillar 3) – Register the CA as an IAM Roles Anywhere trust anchor and issue ML-DSA certificates to build agents, ensuring the signer’s identity chains back to the same quantum-resistant root of trust.
  3. Artifact signing (Pillars 4 and 5) – Sign binaries, container images, and SBOMs using the authenticated build agent.
  4. Verification and enforcement – Validate signatures at deployment and enforce ML-DSA-only policies.

Prerequisites

To follow along, you need:

  • An AWS account with permissions to create resources in AWS KMS, AWS Private CA, IAM Roles Anywhere, and Amazon ECR.
  • AWS Command Line Interface (AWS CLI) v2 configured with appropriate credentials.
  • IAM Roles Anywhere credential helper (aws_signing_helper) v1.8.0 or later, the first release that supports ML-DSA keys and certificates, for workload authentication. Download from the IAM Roles Anywhere documentation.
  • OpenSSL 3.5 or later (required for ML-DSA signature verification and mu computation).
  • ORAS CLI v1.2 or later (for attaching Open Container Initiative (OCI) referrer artifacts to container images). Alternatively, you can use the Notation CLI with a custom plugin or any OCI-compliant client that supports the OCI Referrers API.
  • jq, for constructing and parsing the in-toto Statements used for SBOM attestation and for parsing ORAS output.
  • Amazon Inspector SBOM Generator (Sbomgen), or another tool that produces a CycloneDX JSON SBOM, for the SBOM example. Sbomgen runs only on Linux (x86-64 and ARM64), so run that step on a Linux build agent or container. It uses the registry credentials that oras login stores in the Docker config file, and it also accepts them through --username or the INSPECTOR_SBOMGEN_USERNAME and INSPECTOR_SBOMGEN_PASSWORD environment variables.
  • Java 11 or later and Apache Maven, to run the diy-code-signing-kms-private-ca sample that produces the code-signing CSR in Step 4 of Building the ML-DSA PKI foundation.
  • A container image pushed to Amazon ECR (for the container signing example).

Building the ML-DSA PKI foundation

Start by creating the certificate hierarchy that will anchor your supply chain trust. AWS Private CA generates and stores its own CA signing keys internally in hardware-protected HSMs when you create a certificate authority. Use ML-DSA-87 (NIST security category 5, defined as at least as hard to break as exhaustive key search on AES-256) for the root CA because it protects the longest-lived trust anchor. Use ML-DSA-65 (NIST security category 3) for the subordinate CA to balance security with smaller signature sizes for frequently issued certificates.

The parameter sets used here, ML-DSA-87 and ML-DSA-65, are also the approved set in the example algorithm policy that Part 2 of this series turns into enforceable controls. If your organization has standardized on a different set, substitute it in the commands that follow; the build steps don’t change.

Step 1: Create the root CA in AWS Private CA

When you specify KeyAlgorithm: ML_DSA_87, Private CA generates an ML-DSA-87 key pair internally. You don’t need to create a separate AWS KMS key for the CA.

aws acm-pca create-certificate-authority \
  --certificate-authority-configuration '{
    "KeyAlgorithm": "ML_DSA_87",
    "SigningAlgorithm": "ML_DSA_87",
    "Subject": {
      "CommonName": "PQC Supply Chain Root CA",
      "Organization": "Example Corp",
      "Country": "US"
    }
  }' \
  --certificate-authority-type ROOT

After creation, the root CA is in PENDING_CERTIFICATE state. Activate it by self-signing its certificate. This is where you set the root CA’s validity period (10 years is typical for a root):

# Retrieve the root CA's CSR
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <root-ca-arn> \
  --output text > root-ca.csr

# Self-sign the root CA certificate (valid for 10 years)
ROOT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://root-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=3650,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/RootCACertificate/V1 \
  --query CertificateArn --output text)

# Retrieve and install the self-signed root certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $ROOT_CERT_ARN \
  --query Certificate --output text > root-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate fileb://root-ca-cert.pem

Step 2: Create a subordinate CA for code signing

aws acm-pca create-certificate-authority \
  --certificate-authority-configuration '{
    "KeyAlgorithm": "ML_DSA_65",
    "SigningAlgorithm": "ML_DSA_65",
    "Subject": {
      "CommonName": "PQC Code Signing CA",
      "Organization": "Example Corp",
      "Country": "US"
    }
  }' \
  --certificate-authority-type SUBORDINATE

After creation, the subordinate CA enters PENDING_CERTIFICATE state with no link to the root. Activate it by signing its certificate signing request (CSR) with the root CA:

# Retrieve the subordinate CA's certificate signing request
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <sub-ca-arn> \
  --output text > sub-ca.csr

# Sign the CSR using the root CA (this establishes the trust hierarchy)
SUB_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://sub-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=1825,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/SubordinateCACertificate_PathLen0/V1 \
  --query CertificateArn --output text)

# Retrieve the signed certificate and import it to activate the subordinate CA
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $SUB_CERT_ARN \
  --query Certificate --output text > sub-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate fileb://sub-ca-cert.pem \
  --certificate-chain fileb://root-ca-cert.pem

Step 3: Create the code-signing key in AWS KMS

Your build agents use this key to sign artifacts, so their IAM roles need the kms:Sign permission on it. The end-entity certificate issued by your subordinate CA binds an identity to this key’s public key.

aws kms create-key \
  --key-spec ML_DSA_65 \
  --key-usage SIGN_VERIFY \
  --description "PQC code-signing key for supply chain" \
  --tags TagKey=Purpose,TagValue=CodeSigning

Create an alias for convenient reference in your CI/CD scripts:

aws kms create-alias \
  --alias-name alias/pqc-code-signing \
  --target-key-id <key-id-from-above>

Step 4: Issue the end-entity code signing certificate

To issue a certificate, you need a CSR. Because the ML-DSA private key never leaves the AWS KMS HSM, you can’t generate the CSR locally with OpenSSL. Instead, you construct the CSR’s TBS (to-be-signed) structure containing your subject name and public key, sign it remotely by calling aws kms sign, and assemble the final CSR from those components.

For a working implementation that assembles an ML-DSA CSR around a KMS-managed private key and signs it with AWS KMS, see Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS and its diy-code-signing-kms-private-ca sample on GitHub (Java, built with Maven). There is no AWS CLI-only path for this step: the CSR must be constructed and signed in code, and the sample is the reference implementation.

After you have the code-signing.csr file, issue the certificate from your subordinate CA:

# Issue a code-signing certificate valid for one year, signed by the subordinate CA using ML-DSA-65.
# Replace <sub-ca-arn> with the ARN that create-certificate-authority returned for the subordinate CA in Step 2.
CODE_SIGNING_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --csr fileb://code-signing.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=365,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/CodeSigningCertificate/V1 \
  --query CertificateArn --output text)

# Retrieve the issued certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-arn $CODE_SIGNING_CERT_ARN \
  --query Certificate --output text > code-signing-cert.pem

This certificate binds the signer identity to the AWS KMS code-signing key material. Note that the certificate validity period (365 days in this example) determines how long verifiers can validate signatures by checking the certificate alone. AWS Private CA lets you choose the validity period of an issued certificate, as long as it ends no later than the issuing CA’s own certificate; in this example the subordinate CA certificate from Step 2 is valid for 1,825 days, so the three-year option below fits inside it. For artifacts that must remain verifiable beyond the certificate’s expiry, consider these approaches:

  • Longer certificate validity – For private PKI, code-signing certificates are commonly issued with multi-year validity (for example, Value=1095,Type=DAYS for 3 years) because you control the issuance policy.
  • Trusted timestamping (RFC 3161) – Countersign each signature with an RFC 3161 timestamp from a Time Stamping Authority (TSA) at signing time. The timestamp proves the signature was created while the certificate was valid, allowing verification indefinitely. AWS doesn’t provide a managed TSA; use a third-party TSA or operate your own.
  • Re-signing – Before a certificate expires, re-sign active artifacts with a newly issued certificate.

Distribute the certificate chain (root CA certificate, subordinate CA certificate, and end-entity certificate) to systems that need to verify your signatures.

Signing artifacts with ML-DSA in your CI/CD pipeline

With the PKI hierarchy in place, integrate ML-DSA signing into your build process. The approach depends on artifact type. ML-DSA-65 signatures are 3,309 bytes (compared to 64 bytes for ECDSA P-256), and the latency of the AWS KMS Sign operation for ML-DSA is comparable to existing asymmetric operations. The larger signature size has negligible impact when stored alongside multi-megabyte container images or packages, but is worth accounting for in size-constrained environments like embedded device images transmitted over low-bandwidth links.

Binary and package signing

Most build outputs, including compiled binaries and packages, are far larger than the 4,096-byte limit that AWS KMS places on the message passed to aws kms sign. Make the EXTERNAL_MU method your pipeline’s default: compute the 64-byte message representative (mu) externally with OpenSSL 3.5, then pass only mu to AWS KMS. This handles an artifact of any size and never needs to change as your artifacts grow. AWS KMS also accepts content directly with --message-type RAW, up to 4,096 bytes. Use RAW only for inputs whose size is fixed by construction, such as the 71-character manifest digest in the container image example that follows. An artifact that fits today is likely to outgrow the limit later, and a pipeline that depends on RAW fails when it does. Both methods produce cryptographically identical signatures. The verifier doesn’t need to know which method was used; standard ML-DSA verification applies in either case.

# Retrieve the public key
aws kms get-public-key --key-id alias/pqc-code-signing \
  --query PublicKey --output text | base64 --decode > pk.der

# Extract raw public key bytes from the DER-encoded SubjectPublicKeyInfo.
# The BIT STRING starts at offset 17 for all ML-DSA key sizes. 
# Expected output: 1,312 bytes (ML-DSA-44), 1,952 bytes (ML-DSA-65), or 2,592 bytes (ML-DSA-87).

openssl asn1parse -inform DER -in pk.der -strparse 17 -noout -out pk_raw.bin

# Compute mu per FIPS 204 Section 6.2
printf '\x00\x00' | cat - artifact.bin > m_prime.bin
openssl dgst -shake256 -xoflen 64 -binary pk_raw.bin > pk_hash.bin
cat pk_hash.bin m_prime.bin | openssl dgst -shake256 -xoflen 64 -binary > mu.bin

# Sign the mu value
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > artifact.bin.sig

Store the .sig file alongside the artifact in Amazon S3 or your package repository. Protect the integrity of both the artifact and its signature by enabling S3 Object Lock (WORM protection) or at minimum S3 Versioning with restricted write access. If an attacker can modify or delete either file, verification can’t be trusted. For comprehensive guidance, see Security best practices for Amazon S3.

Container image signing

For container image signing, use the OCI referrer pattern, defined in the OCI Image and Distribution Specifications v1.1. A referrer is an artifact, such as a signature or an SBOM, whose manifest names another image in its subject field. Registries that support the pattern, including Amazon ECR, return these artifacts when a client asks for an image’s referrers. This approach uses AWS KMS ML-DSA keys to generate the signature and stores it as a referrer of the image:

# Repository URI used by ORAS here and in the SBOM steps; replace the account ID and Region
ECR_URI=111122223333.dkr.ecr.us-east-1.amazonaws.com/myapp

# Authenticate ORAS to Amazon ECR
aws ecr get-login-password --region us-east-1 | \
  oras login --username AWS --password-stdin 111122223333.dkr.ecr.us-east-1.amazonaws.com

# Get the image manifest digest
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)

# Sign the digest. It is a fixed 71 characters, so RAW is safe here (see Binary and package signing).
# AWS CLI v2 expects blob parameters to be base64, so write the digest to a file and pass it with fileb://
echo -n "$IMAGE_DIGEST" > digest.txt
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://digest.txt \
  --message-type RAW \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > image.mldsa.sig

# Attach signature as OCI referrer using ORAS
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" \
  image.mldsa.sig:application/octet-stream

At deployment time, your admission controller retrieves the referrer artifact and verifies the ML-DSA signature before allowing the image to run. See Verifying a container image signature before deployment later in this post for the full verification workflow and admission control implementation.

SBOM signing

A software bill of materials (SBOM) is a structured inventory of every component, library, and dependency included in a software release. It lists package names, versions, suppliers, and dependency relationships. Organizations use SBOMs to track vulnerabilities, verify license compliance, and respond quickly when a compromised component is disclosed.

Signing the SBOM file on its own proves that the inventory hasn’t been tampered with since it was signed, but not which artifact it describes. If the image signature and the SBOM signature are independent of each other, an attacker who holds a legitimately signed SBOM for a clean image can present it alongside a different signed image and claim that the two correspond. Attaching the SBOM to the image as an OCI referrer doesn’t close this gap by itself, because the subject field of a referrer manifest is set by whoever pushes the referrer; it’s a discovery mechanism, not a cryptographic binding. The binding must be inside the bytes that the signature covers.

To create that binding, wrap the SBOM in an in-toto Statement before signing it. A Statement names the artifacts it describes in its subject field, by digest, and carries the SBOM as its predicate. Because the image manifest digest is part of the signed content, a verifier can confirm that the SBOM in hand was issued for exactly the image it is about to deploy, and a swapped SBOM or a swapped digest fails verification. Embedding the SBOM in the image filesystem is another way to bind the two, because the image digest then covers the SBOM bytes. This post uses the Statement approach because it also works for SBOMs generated by scanning a finished image, for artifacts that have no filesystem such as binaries and firmware, and for images that are already in your registry, and because the SBOM stays readable from the registry without pulling the image.

Generate the SBOM with your preferred tool (such as Amazon Inspector SBOM Generator (Sbomgen) for container images), wrap it in a Statement, and sign the Statement with the same EXTERNAL_MU step you use for binaries:

# Scan the pushed image by digest so the inventory describes exactly the manifest you signed.
# Sbomgen reuses the registry login from the oras login step in the previous section.
inspector-sbomgen container --image $ECR_URI@$IMAGE_DIGEST -o sbom.json

# Wrap the SBOM in an in-toto Statement whose subject is the image manifest digest.
# This puts the digest inside the signed bytes, which binds this SBOM to this image.
jq -n \
  --arg name "$ECR_URI" \
  --arg digest "${IMAGE_DIGEST#sha256:}" \
  --slurpfile sbom sbom.json \
  '{
    "_type": "https://in-toto.io/Statement/v1",
    "subject": [{"name": $name, "digest": {"sha256": $digest}}],
    "predicateType": "https://cyclonedx.org/bom",
    "predicate": $sbom[0]
  }' > sbom.statement.json

# Sign using EXTERNAL_MU (same mu computation as binary signing above,
# with sbom.statement.json as the input)
# ... compute mu from sbom.statement.json ...
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > sbom.statement.json.sig

# Attach the Statement and its signature to the image as an OCI referrer so
# verifiers discover them alongside the image signature
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" \
  sbom.statement.json:application/vnd.in-toto+json \
  sbom.statement.json.sig:application/octet-stream

Ship the Statement and its .sig file together; the SBOM itself is the Statement’s predicate field, and verifiers extract it after verification. The same pattern binds an SBOM to a binary or package: set the subject digest to the SHA-256 of the file instead of an image manifest digest. The Verifying a binary or SBOM signature section later in this post walks through the full verification workflow, including the subject check that completes the binding.

Quantum-resistant workload identity for build agents

Signing artifacts with ML-DSA keys addresses the integrity of the artifacts themselves. Separately, build agents running outside AWS (on-premises Jenkins, self-hosted GitHub Actions runners, or third-party CI/CD systems) authenticate using X.509 certificates or OIDC tokens typically signed with RSA or ECDSA. These authentication credentials represent a classical cryptographic dependency in the pipeline. IAM Roles Anywhere with ML-DSA certificates replaces that dependency: the credential that the external build agent presents, and the CA that vouches for it, no longer rely on algorithms that are vulnerable to quantum attack. (The TLS connection that carries the request still authenticates the AWS endpoint with a traditional certificate, as public TLS does today; that is a transport concern separate from the signing identity this post is about.) Build agents running on AWS with an attached IAM role don’t have this dependency: their API requests are authenticated with AWS Signature Version 4 (SigV4), which uses a symmetric hash-based message authentication code (HMAC-SHA256). Symmetric schemes like this are already considered quantum-resistant, so no additional action is needed.

Step 1: Register a workload identity CA as a trust anchor

For this walkthrough, reuse the subordinate CA that you created earlier; that avoids the monthly charge for a second CA, and the commands that follow assume it. In production, use a dedicated subordinate CA for workload identity certificates, separate from your code-signing CA. This limits the blast radius if either CA is compromised and has to be revoked, and it lets you apply different issuance policies to the two certificate types.

# Use the ARN that create-certificate-authority returned when you created the
# subordinate CA earlier. If you no longer have it, list your CAs and copy the
# ARN of the SUBORDINATE one.
aws acm-pca list-certificate-authorities \
  --query "CertificateAuthorities[?Type=='SUBORDINATE'].[Arn,Status,CertificateAuthorityConfiguration.Subject.CommonName]" \
  --output table
SUB_CA_ARN=arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/abc-123   # replace with yours

# Register the subordinate CA as an IAM Roles Anywhere trust anchor
aws rolesanywhere create-trust-anchor \
  --name "PQC-CI-CD-Trust-Anchor" \
  --source "sourceType=AWS_ACM_PCA,sourceData={acmPcaArn=$SUB_CA_ARN}" \
  --enabled

Step 2: Create the build agent role and a profile that references it

An IAM Roles Anywhere profile specifies which IAM roles a workload can assume after it authenticates with a certificate from your trust anchor. Create the role first. Its trust policy lets IAM Roles Anywhere assume it only through your trust anchor and only for a certificate whose subject common name identifies the build agent; without those conditions, any certificate that the trust anchor CA issues could assume the role. Its permissions policy grants only what signing requires, on only the code-signing key. Save the trust policy as build-agent-trust.json, replacing the trust anchor ARN with the one that create-trust-anchor returned in Step 1:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {"Service": "rolesanywhere.amazonaws.com"},
      "Action": ["sts:AssumeRole", "sts:TagSession", "sts:SetSourceIdentity"],
      "Condition": {
        "ArnEquals": {
          "aws:SourceArn": "arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id"
        },
        "StringEquals": {
          "aws:PrincipalTag/x509Subject/CN": "pqc-build-agent-01"
        }
      }
    }
  ]
}

Save the permissions policy as build-agent-permissions.json, replacing the resource with your key’s ARN (aws kms describe-key --key-id alias/pqc-code-signing --query KeyMetadata.Arn --output text):

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["kms:Sign", "kms:GetPublicKey", "kms:DescribeKey"],
      "Resource": "<code-signing-key-arn>"
    }
  ]
}

Create the role, attach the policy, and then create a profile that references the role:

aws iam create-role \
  --role-name PQCBuildAgentRole \
  --assume-role-policy-document file://build-agent-trust.json

aws iam put-role-policy \
  --role-name PQCBuildAgentRole \
  --policy-name pqc-code-signing \
  --policy-document file://build-agent-permissions.json

aws rolesanywhere create-profile \
  --name "PQC-Build-Agent-Profile" \
  --role-arns "arn:aws:iam::111122223333:role/PQCBuildAgentRole" \
  --enabled

Step 3: Issue the build agent certificate and configure the credential helper

Generate the build agent’s ML-DSA-65 key pair and CSR locally with OpenSSL, have the subordinate CA issue a client authentication certificate for it, and then configure the IAM Roles Anywhere credential helper to present that certificate:

# Generate the build agent's key pair and CSR. The CN must match the
# aws:PrincipalTag/x509Subject/CN condition in the role's trust policy.
openssl genpkey -algorithm ML-DSA-65 -out build-agent-mldsa-key.pem
chmod 400 build-agent-mldsa-key.pem
openssl req -new -key build-agent-mldsa-key.pem \
  -subj "/C=US/O=Example Corp/CN=pqc-build-agent-01" \
  -out build-agent.csr

# Issue a 30-day client authentication certificate from the subordinate CA
# registered as the trust anchor in Step 1.
BUILD_AGENT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --csr fileb://build-agent.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=30,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/EndEntityClientAuthCertificate/V1 \
  --query CertificateArn --output text)

aws acm-pca get-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --certificate-arn $BUILD_AGENT_CERT_ARN \
  --query Certificate --output text > build-agent-mldsa.pem

# In production, store the private key in a TPM or HSM rather than as a plaintext file.
aws_signing_helper credential-process \
  --certificate build-agent-mldsa.pem \
  --private-key build-agent-mldsa-key.pem \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111122223333:profile/profile-id \
  --role-arn arn:aws:iam::111122223333:role/PQCBuildAgentRole

The helper produces short-lived AWS Security Token Service (AWS STS) credentials scoped to the build role, replacing long-lived AWS access keys. In production, protect the ML-DSA private key with hardware-backed storage such as a Trusted Platform Module (TPM), an HSM, or an encrypted credential store with restricted file permissions. The plaintext file path shown here is for demonstration purposes. The private key authorizes access to your code-signing infrastructure and should be treated with the same protection level as any signing key. On Linux build agents, at minimum restrict the file to chmod 400 owned by the service account and consider using a PKCS#11 provider to avoid storing the raw key on disk entirely.

Verification and policy enforcement

A signing architecture is only as strong as its verification. Producing signatures is half the story. The other half is giving the systems and people that deploy your artifacts, such as deployment pipelines, Kubernetes admission controllers, and engineers installing a package, a concrete way to verify those signatures and make trust decisions before an artifact is deployed or run.

Distributing your trust chain

Before any verifier can check a signature, it needs to trust the CA that issued the code-signing certificate. This trust is established through a trust store: a local collection of root CA certificates that a system treats as authoritative. Trust stores exist in operating systems (such as /etc/pki/ca-trust/ on Linux, Keychain on macOS), language run-times (Java cacerts), container base images, and custom application configurations.

For private PKI hierarchies like the one in this post, your root CA certificate isn’t in any default public trust store. You must explicitly add it to the trust stores of every system that will verify your signatures. Common approaches include:

  • Baking the root CA certificate into your container base images during the build process
  • Distributing it through configuration management (AWS Systems Manager Parameter Store, AWS Secrets Manager, or your existing configuration tooling)
  • Publishing it to an internal S3 bucket with versioning and access logging
  • Storing it as an OCI artifact in Amazon ECR alongside the images it protects

Treat trust store management with the same rigor as credential management. If an attacker can inject a rogue root certificate into your trust stores, they can make forged signatures appear valid. Restrict write access to trust stores and audit changes through AWS CloudTrail or your system-level audit logs.

Exporting your certificate chain requires exporting the root CA, and then any subordinate CAs that issue certificates that will be involved in verifying signatures:

# Export the root CA certificate
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --query Certificate --output text > root-ca.pem

# Export the subordinate CA certificate. Select only the Certificate field: for a
# subordinate CA this call also returns CertificateChain, and --output text would
# print both on one tab-separated line, producing a file that OpenSSL can't parse.
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --query Certificate --output text > sub-ca.pem
  
# Bundle the full chain for verifiers
cat root-ca.pem sub-ca.pem > trust-chain.pem

Verifiers use this chain to confirm that the code-signing public key was issued by a CA they trust.

The CAs in this post are created without a revocation configuration, and the verification commands that follow don’t check revocation status, which keeps the walkthrough short. In production, configure a certificate revocation list (CRL) or an Online Certificate Status Protocol (OCSP) responder on the subordinate CA (see Plan your AWS Private CA certificate revocation method in the AWS Private CA User Guide; both work with ML-DSA CAs). If you use a CRL, distribute it alongside the trust chain and add -crl_check -CRLfile <crl-file> to the openssl verify command below, where <crl-file> is the CRL that AWS Private CA publishes to your S3 bucket, so that a revoked code-signing certificate fails verification.

Verifying a binary or SBOM signature

Verify the code-signing certificate against the trust chain, confirm that it is a code-signing certificate issued to the signer you expect, extract its public key, and then verify the signature with OpenSSL 3.5. The second check matters: a chain check alone accepts every certificate that the CA hierarchy has issued, including the build agent client certificates from the previous section, so pin the expected subject in your verifier configuration:

# Step 1: Verify that the code-signing certificate chains to the trusted root CA and carries the
# Code Signing extended key usage. -purpose codesign (OpenSSL 3.2 and later) rejects a certificate
# that chains correctly but was issued for another purpose, such as a build agent's client
# authentication certificate from the same subordinate CA.
# trust-chain.pem contains the root CA and subordinate CA certificates distributed in the previous section.
openssl verify -CAfile trust-chain.pem -purpose codesign code-signing-cert.pem
# Confirm that the certificate was issued to the signer you expect. Replace <signer-cn> with the
# common name in your code-signing certificate's subject.
openssl x509 -in code-signing-cert.pem -noout -subject -nameopt RFC2253 | grep -q "CN=<signer-cn>" || { echo "Unexpected signer"; exit 1; }

# Step 2: Extract the public key from the verified certificate.
openssl x509 -in code-signing-cert.pem -pubkey -noout > signing-key.pem

# Step 3: Verify the artifact signature using the trusted public key.
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in artifact.bin \
  -sigfile artifact.bin.sig \
  -rawin

A successful verification prints Signature Verified Successfully and returns an exit status of 0. A failed verification prints Signature Verification Failure and returns a nonzero exit status. In shell scripts, check the exit status of each command, or run the block with set -e, so that a failed certificate chain check stops the script before signature verification and a failed signature check blocks downstream actions.

For an SBOM, run the same three steps with sbom.statement.json as the -in file and sbom.statement.json.sig as the -sigfile, then add a fourth: confirm that the subject digest inside the verified Statement is the digest of the artifact you are about to deploy. Signature verification proves the Statement is authentic; the subject check proves it describes this artifact and not another one. The digest you compare against must come from the artifact itself, resolved from the registry for an image or computed from the file for a binary, never from the Statement. For an image, this is the same digest you verify the image signature against, so the two checks together establish that this SBOM describes this signed image.

# Step 4 (SBOM only): the signed Statement must name the image being deployed.
# Resolve the digest from Amazon ECR, not from the Statement.
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)
SUBJECT_DIGEST=$(jq -r '.subject[0].digest.sha256' sbom.statement.json)
[ "sha256:$SUBJECT_DIGEST" = "$IMAGE_DIGEST" ] || { echo "SBOM does not describe this image"; exit 1; }

# Only now extract the SBOM for downstream tooling
jq '.predicate' sbom.statement.json > sbom.json

For a binary, compare the subject digest to the output of sha256sum artifact.bin instead. Reject the SBOM if either the signature or the subject check fails.

Verifying a container image signature before deployment

Pull the ML-DSA signature from the OCI referrer artifact in Amazon ECR, then verify it against the image manifest digest:

# Pull the signature referrer. ORAS 1.2 lists referrers under "manifests";
# ORAS 1.3 and later list them under "referrers". The jq filter accepts either.
oras discover $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" --format json | \
  jq -r '(.referrers // .manifests)[0].digest' | \
  xargs -I{} oras pull $ECR_URI@{} -o /tmp/sig/

# Re-derive the image digest and verify
echo -n "$IMAGE_DIGEST" > /tmp/digest.txt
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in /tmp/digest.txt \
  -sigfile /tmp/sig/image.mldsa.sig \
  -rawin

# Exit code 0 = image is authentic; non-zero = reject deployment

The same oras discover command with --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" retrieves the SBOM attestation and its signature; verify them as described in the previous section, including the subject check. The jq filter shown takes the first referrer of the requested type. Don’t rely on the order in which a registry lists referrers, and expect more than one after an image has been re-signed: a production verifier should check every referrer of that type and accept the image if at least one signature verifies against a certificate that chains to your trust store. Taking only the first can reject a correctly signed image, but it can never accept an unsigned one.

To enforce these checks at deployment time, run them in a Kubernetes admission controller, a component that the API server calls before it accepts a pod and that can reject the request. You can write one as a validating admission webhook (see Dynamic Admission Control in the Kubernetes documentation), or use Open Policy Agent (OPA) Gatekeeper, an admission webhook that enforces policies evaluated by the OPA policy engine, and package the verification steps as a Gatekeeper external data provider that a constraint calls. For a worked example of gating Amazon EKS deployments on image signatures, see Announcing Container Image Signing with AWS Signer and Amazon EKS, which verifies AWS Signer signatures at admission with Kyverno and discusses the Gatekeeper and custom webhook alternatives. The ML-DSA signature referrer in this post is a custom artifact type that those tools don’t verify out of the box, so the verification steps in this section run in code you supply. In either design, the controller runs before any pod is scheduled, rejecting images that lack a valid ML-DSA signature referrer in Amazon ECR or whose SBOM attestation doesn’t name the image being deployed.

Preventive and detective controls

Signature verification stops the use of an untrusted artifact at deployment. Organization-level controls apply earlier and more broadly: preventive controls stop teams from creating new traditional signing keys, and detective controls record every signing operation so you can audit which principal signed each artifact and when.

Preventive guardrails. Use an AWS Organizations Service control policy (SCP) to block creation of traditional signing keys in security-critical accounts, forcing all new signing workloads to use ML-DSA:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RequirePQCSigningKeys",
      "Effect": "Deny",
      "Action": "kms:CreateKey",
      "Resource": "*",
      "Condition": {
        "StringNotLike": {
          "kms:KeySpec": "ML_DSA_*"
        },
        "StringEquals": {
          "kms:KeyUsage": "SIGN_VERIFY"
        }
      }
    }
  ]
}

This SCP prevents teams from creating new RSA or ECDSA signing keys, enforcing quantum-resistant signatures as the only option for new workloads. Note that this SCP constrains the algorithm family, not the parameter set: it would still permit an ML-DSA-44 key, which this architecture doesn’t use. Part 2 of this series picks up at exactly this point. It shows how to express a complete algorithm policy (in its example, approve ML-DSA-65 and ML-DSA-87 and exclude ML-DSA-44) as layered controls using the kms:KeySpec condition key in SCPs, IAM permission boundaries, and AWS KMS key policies; how to restrict the use of keys that already exist; and how to govern surfaces such as AWS Private CA that have no algorithm condition key. This SCP and the parameter-set SCP in Part 2 work together: attach both, and every new signing key must use an approved parameter set.

Audit trail. AWS CloudTrail logs every kms:Sign and kms:Verify API call, providing an immutable record of when each artifact was signed and by which principal. Use an organization trail and query its logs with Amazon Athena to analyze signing activity across accounts and correlate it with your deployment events.

Regulatory timeline and recommended actions

The following table maps regulatory milestones to specific actions you can take today using the architecture described in this post. This information is provided for general awareness only and does not constitute legal or compliance advice. Consult your legal and compliance teams to determine your organization’s specific obligations. For a broader overview of global PQC regulatory timelines, see Migrating to Post-Quantum Cryptography.

Regulation Deadline Regulatory language Action on AWS
CNSA 2.0: Support and prefer 2025 (in effect) CNSA 2.0 timeline (Sep 2022, FAQ v2.1 Dec 2024): Software and firmware signing must “support and prefer” CNSA 2.0 algorithms by 2025 Create ML-DSA keys in AWS KMS, begin signing artifacts with ML-DSA alongside existing traditional signatures
CNSA 2.0: New system acquisitions January 2027 CNSA 2.0 FAQ v2.1 (Dec 2024): “All new NSS acquisitions must be CNSA 2.0 compliant at deployment, effective 1 January 2027” Full ML-DSA PKI operational, IAM Roles Anywhere trust anchors using ML-DSA, all new builds carry ML-DSA signatures
EU Cyber Resilience Act 11 December 2027 Regulation (EU) 2024/2847, Annex I, Part I(2)(f): Products must “protect the integrity of stored, transmitted or otherwise processed data, personal or other, commands, programs and configuration against any manipulation or modification not authorised by the user, and report on corruptions”; Part II(7): Manufacturers must “provide for mechanisms to securely distribute updates” ML-DSA code signing for all software updates shipped to EU markets, signed SBOMs accompany every release
CNSA 2.0: Exclusive use 2030 CNSA 2.0 timeline: Software and firmware signing must “exclusively use” CNSA 2.0 algorithms by 2030 Remove traditional signing keys from supply chain, SCP enforcement of ML-DSA-only key creation
PCI DSS 4.0 Req 12.3.3 Mandatory since March 2025 PCI DSS v4.0.1, Requirement 12.3.3: “Cryptographic cipher suites and protocols in use are documented and reviewed at least once every 12 months”, including an up-to-date inventory of the cipher suites and protocols in use Document cryptographic inventory in AWS KMS, tag ML-DSA versus traditional keys, maintain migration progress tracking

Note for NSS customers and other CNSA 2.0 adopters: CNSA 2.0 is the quantum-resistant algorithm suite that the NSA requires for NSS, the federal systems that carry classified information or support intelligence, cryptologic, military command and control, and weapons functions. When ML-DSA is used for any signature purpose, including software and firmware signing, CNSA 2.0 permits only the ML-DSA-87 parameter set. (For software and firmware signing it also approves the stateful hash-based schemes LMS and XMSS, which this post doesn’t cover.) The ML-DSA-65 parameter set used in this post’s code-signing examples is appropriate for commercial workloads but isn’t permitted on NSS. CNSA 2.0 is binding only for NSS, but it’s followed voluntarily well beyond that boundary: by suppliers to the US defense and intelligence market, in the United States and allied countries, whose products must meet NSS requirements, and by commercial organizations in and outside the United States that adopt it as a conservative baseline because it specifies the highest NIST security category and removes the need to revisit parameter choices later. If your systems fall under CNSA 2.0 scope, or you’ve chosen to align with it, substitute ML-DSA-87 for all signing keys and certificates. Part 2 of this series shows how to make that substitution enforceable: the same kms:KeySpec controls that exclude ML-DSA-44 in its example can be pointed at ML_DSA_87 as the only approved key spec.

For organizations serving both US government and EU commercial markets, the January 2027 and December 2027 deadlines converge into a single migration window. Starting now provides margin for testing, key rotation planning, and certificate chain validation.

Clean up

You created a number of cryptographic resources in the prior steps and examples. AWS Private CA charges a monthly fee per CA and AWS KMS charges per key per month. To avoid ongoing charges, delete them if you aren’t actively using them. Start by listing what exists, so that you catch every resource you created, including duplicates from repeated runs. These commands list one Region; if you worked in more than one, repeat them with --region for each.

# List every private CA with its type, status, key algorithm, and subject.
# A CA you already deleted shows DELETED until its restoration window ends.
aws acm-pca list-certificate-authorities \
  --query 'CertificateAuthorities[].[Arn,Type,Status,CertificateAuthorityConfiguration.KeyAlgorithm,CertificateAuthorityConfiguration.Subject.CommonName]' \
  --output table

# List every ML-DSA key in AWS KMS with its state and creation date.
# A key already scheduled for deletion shows PendingDeletion.
for KEY_ID in $(aws kms list-keys --query 'Keys[].KeyId' --output text); do
  aws kms describe-key --key-id "$KEY_ID" \
    --query 'KeyMetadata.[KeyId,KeySpec,KeyState,CreationDate]' --output text
done | grep ML_DSA

# Show which alias points at which key. A key that no alias points at
# is usually a leftover from an earlier run.
aws kms list-aliases --query 'Aliases[].[AliasName,TargetKeyId]' --output text | grep -v '^alias/aws/'

AWS Private CA has no command that lists the certificates a CA has issued. If you need serial numbers for the revocation step that follows, generate an audit report with aws acm-pca create-certificate-authority-audit-report, which writes a list of every certificate the CA has issued or revoked to an S3 bucket that grants the service write access.

Delete each resource that you don’t need, including any extra copies that the listing revealed, then run the listing again to confirm that nothing is left:

# Revoke any issued end-entity certificates while the subordinate CA is still active
aws acm-pca revoke-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-serial <serial-number> \
  --revocation-reason CESSATION_OF_OPERATION

# Delete the IAM Roles Anywhere resources that reference the CA
aws rolesanywhere delete-profile --profile-id <profile-id>
aws rolesanywhere delete-trust-anchor --trust-anchor-id <trust-anchor-id>

# Delete the build agent role that the profile referenced, and the local copy of its private key
aws iam delete-role-policy --role-name PQCBuildAgentRole --policy-name pqc-code-signing
aws iam delete-role --role-name PQCBuildAgentRole
rm -f build-agent-mldsa-key.pem

# Delete the AWS KMS code-signing key (schedule 7-day waiting period).
# ScheduleKeyDeletion doesn't accept an alias, so resolve the key ID first.
KEY_ID=$(aws kms describe-key --key-id alias/pqc-code-signing \
  --query KeyMetadata.KeyId --output text)
aws kms schedule-key-deletion --key-id $KEY_ID --pending-window-in-days 7

# Remove the alias. It survives key deletion and would otherwise show up in the
# listing above on your next run.
aws kms delete-alias --alias-name alias/pqc-code-signing

# Disable and delete the subordinate CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --permanent-deletion-time-in-days 7

# Disable and delete the root CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --permanent-deletion-time-in-days 7

If you are adapting this for long-term use, plan for log retention. CloudTrail Event History keeps only the last 90 days of management events and is not a substitute for a trail. For the audit trail described earlier, create a trail that delivers to an S3 bucket with the lifecycle policy and access controls your retention requirements call for.

Conclusion

In this post, I showed you how to build a quantum-resistant software supply chain on AWS by combining ML-DSA signing in AWS KMS, ML-DSA certificate hierarchies in AWS Private CA, and ML-DSA workload authentication through IAM Roles Anywhere. The architecture covers the full pipeline; from authenticated build agents through signed binaries, container images, and SBOMs, to verification and policy enforcement at deployment.

Every ML-DSA capability used in this post is generally available. AWS Private CA and IAM Roles Anywhere support ML-DSA in all commercial AWS Regions, the AWS GovCloud (US) Regions, and the China Regions, and AWS KMS supports ML-DSA in commercial AWS Regions. You don’t need to wait for a standards body or third-party tool to finalize PQC support. The primitives are ready.

To get started, create your first ML-DSA key in AWS KMS and sign a test artifact. From there, extend to your PKI hierarchy, integrate IAM Roles Anywhere for your build agents, and add ML-DSA signatures to your container and SBOM workflows.

Building the pipeline is half the work. The other half is making sure the algorithm choices you made stay in force as accounts, teams, and standards change. That’s the subject of Part 2 of this series, Enforce your ML-DSA algorithm policy with SCPs and IAM, written for the security and governance teams who own that problem.

For more information, see:

If you have feedback about this post, submit comments in the Comments section below.

Harshvardhan Chunawala

Harshvardhan Chunawala

Harshvardhan is a Solutions Architect and Security SME at AWS, where he leads cross-team efforts with Amazon Leo, Amazon Security, and AWS Agentic AI. A Golden Jacket awardee with over a decade in cloud security, he’s an advisory board member, Visiting Faculty, and researcher at Carnegie Mellon University. He advises C-suite executives, enterprise leaders, and startup founders worldwide on building secure, scalable cloud platforms.

Operationalizing least privilege: Automate IAM remediation through your CI/CD pipeline

Post Syndicated from Luis Pastor original https://aws.amazon.com/blogs/security/operationalizing-least-privilege-automate-iam-remediation-through-your-ci-cd-pipeline/

The principle of least privilege is straightforward to articulate but challenging to maintain at scale. When teams first deploy applications to AWS, they often grant broader permissions than strictly necessary; it’s faster to get things working, and the plan is always to tighten permissions later. But later rarely comes. Permissions accumulate, AWS Identity and Access Management (IAM) principals that once needed broad access for initial deployment retain those permissions long after they’re necessary, and some principals stop being used entirely. Even small teams face this challenge—permission reviews aren’t a one-time task but an ongoing operational burden that demands automation.

AWS IAM Access Analyzer addresses detection and recommendation. It identifies unused permissions across IAM roles and users: actions that haven’t been exercised, services that haven’t been accessed, and principals that aren’t being assumed at all. For each finding, it generates a recommended policy with the excess permissions removed. Security teams can see exactly what to fix, but manual remediation doesn’t persist. A security engineer can right-size a role today, but if that role is defined in an AWS CloudFormation template or AWS Cloud Development Kit (AWS CDK) stack, the next deployment restores the original permissions. The fix must live where the role is defined, and not every role starts in the same place. Some are managed through infrastructure-as-code (IaC), where remediation means updating source code and deploying through a pipeline. Others were created manually through the AWS Management Console and have no code representation. And some principals aren’t being used at all and need a controlled decommission path. Each scenario requires a different remediation strategy.

This post walks through an automated remediation workflow that bridges the gap between detection and action. Instead of findings accumulating in a dashboard waiting for someone to investigate, the automation classifies each role by how it was created and produces a ready-to-review remediation artifact: a pull request with production-ready CDK code and a plain-English explanation for IaC-managed roles, an issue with the recommended policy and step-by-step IaC migration guidance for manually created roles, or a soft-disable issue with a monitored decommission plan for unused principals. Each output flows through your existing code review and issue tracking processes—the same workflows your teams already follow. By the end of this post, you’ll have a pattern that converts IAM Access Analyzer findings into tested, deployable code changes rather than a growing backlog of security tickets.

Understanding the problem

Unused IAM permissions increase the attack surface. Removing unused permissions limits the actions available to any compromised credentials, reducing potential impact. Roles that aren’t being assumed represent unused resources; removing them simplifies your IAM inventory and reduces potential access paths that aren’t actively monitored.

The challenge isn’t knowing what to fix. As we said earlier, Access Analyzer provides both the findings and the recommended policies. The challenge is acting on that knowledge consistently across your environment. Each finding requires context:

  • What the role does
  • Who created the role
  • Determining if the permission is unused or used infrequently
  • If the role is managed in a CloudFormation stack, or was created through the console

Multiply this by hundreds of roles and security teams face a backlog that grows faster than they can address it.

Manual remediation compounds the problem. A security engineer can right-size a role directly in the console, but that fix is fragile. If the role is defined in an IaC template, the next deployment restores the original permissions. If it was created manually, there’s no record of what changed or why, and no easy way to revert if the change causes issues.

This is where IaC changes the equation. When roles are defined in code, remediation means updating that code. Changes flow through pull requests, are reviewed by the team that owns the role, and deploy consistently across environments. The fix becomes permanent, not a point-in-time correction that drifts back on the next deployment. And because every change is tracked in version control, teams can confidently remove permissions knowing they can revert if something breaks. That safety net matters; it’s often the difference between a team acting on a finding and leaving it in the backlog.

Solution overview

The solution automates remediation by connecting four capabilities: IAM Access Analyzer for detection and policy recommendations, CloudTrail for role attribution, Amazon Bedrock for CDK code generation and plain-English explanations, and your existing continuous integration and delivery (CI/CD) pipeline for remediation execution. The workflow operates on a core principle: every IAM role has an origin, and that origin determines the remediation path.

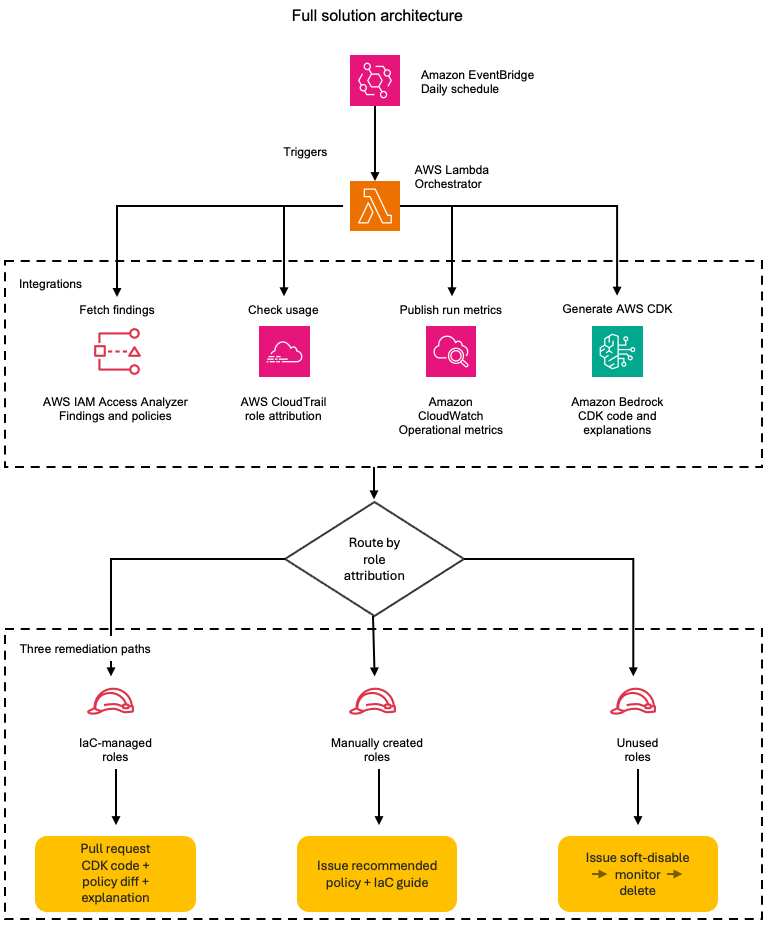
Figure 1 shows the solution architecture: Amazon EventBridge triggers an AWS Lambda orchestrator on a daily schedule. The Lambda orchestrator integrates with IAM Access Analyzer, CloudTrail, Amazon Bedrock, and Amazon CloudWatch. Each finding is routed to one of three remediation paths: a pull request for IaC-managed roles, an issue for manually created roles, and a soft-disable issue for unused roles.

Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths

Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths

On each scheduled run, the automation retrieves active findings from IAM Access Analyzer and queries CloudTrail to determine how each role was created. Roles created through CloudFormation or AWS CDK have a traceable origin: the service principal, stack name, and originating repository. Roles created manually through the console have a different origin: the IAM user who created them and the timestamp. This distinction drives the remediation strategy.

For IaC-managed roles, the automation retrieves the IAM Access Analyzer-recommended policy and uses Amazon Bedrock to wrap it in production-ready CDK code that includes the role definition and policy statements and imports what your CI/CD pipeline needs to deploy the update. It then creates a pull request in the originating repository. The pull request (PR) includes the updated CDK code, a policy diff showing exactly which permissions are being removed, and a plain-English explanation of the changes, for example, “This change removes write access to S3, keeping only read and list permissions.” Your existing code review process evaluates the change, and after being merged, the fix deploys consistently across environments.

For manually created roles, the automation creates an issue that includes the IAM Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, and an Amazon Bedrock-generated explanation of what the permission changes accomplish. The issue also provides guidance on importing the role into your IaC codebase. This gives teams an immediate remediation path while encouraging long-term governance through IaC adoption.

For roles that aren’t being assumed at all, the automation takes a more cautious approach. Instead of taking direct action, it creates an issue recommending a soft-disable workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. The issue provides the steps and context, the team executes the decommission through their preferred process, whether that’s a console change, an AWS Command Line Interface (AWS CLI) script, or a PR removing the role from the IaC. This controlled decommission path reduces the risk of removing a role that’s used infrequently or seasonally.

The solution supports both single-account and organization-wide deployment. In single-account mode, it uses an ACCOUNT_UNUSED_ACCESS analyzer to process findings for one account. In organization mode, it uses an ORGANIZATION_UNUSED_ACCESS analyzer deployed in a delegated administrator account, which generates findings across all member accounts from a single vantage point. The Lambda function automatically detects which analyzer type is available and extracts the account ID from each finding’s resource Amazon Resource Name (ARN), so role attribution and remediation routing work the same way regardless of scope.

This three-path strategy acknowledges operational reality. Not all roles start in IaC, not all unused roles are safe to delete immediately, and forcing immediate migration isn’t always practical. The solution provides a clear path forward for each scenario: remediate IaC roles through code, give teams actionable recommendations for manually created roles, and safely decommission what’s no longer needed. Over time, your infrastructure becomes increasingly code-driven, and remediation becomes a routine part of your CI/CD process rather than a manual security task.

Technical details

Consider a company—call them AnyCompany—running 200 IAM roles across three AWS accounts. Some roles were created through AWS CDK stacks during initial deployment. Others were created manually through the console by engineers who needed quick access during incident response or prototyping. A handful haven’t been assumed in over 6 months. AnyCompany’s security team wants to act on their IAM Access Analyzer findings, but each role requires different handling. The solution’s architecture addresses this by routing each finding through a classification and remediation pipeline.

Figure 2 shows how each IAM Access Analyzer finding is processed:

  1. The finding is first checked against exclusions and excluded findings are skipped.
  2. Remaining findings are split by type: UnusedPermission findings retrieve a recommended policy from IAM Access Analyzer and then query CloudTrail for role origin, while UnusedIAMRole findings follow the unused role path.
  3. By origin, IaC-managed roles generate AWS CDK code using Amazon Bedrock and create a pull request.
  4. Manually created or unknown-origin roles create an issue with the recommended policy and IaC migration guidance.
  5. Unused roles create a soft-disable issue to deny-all, monitor for 30 days, then delete.
  6. All paths publish CloudWatch metrics.
Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths

Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths

The rest of this section walks through each component using AnyCompany’s roles as examples.

Exclusion filtering

Before processing any finding, the Lambda function loads an exclusion configuration and checks whether the role should be skipped. This prevents the automation from creating remediation items for roles that legitimately need broad permissions.

{
  "excluded_roles": [
    "arn:aws:iam::123456789012:role/BreakGlassRole",
    "arn:aws:iam::123456789012:role/ServiceLinkedRole"
  ],
  "excluded_permissions": [
    "iam:*",
    "sts:AssumeRole"
  ],
  "excluded_by_tag": {
    "NoRemediation": ["true"],
    "CriticalService": ["true"]
  },
  "min_unused_days": 30
}

AnyCompany excludes their break-glass role (used only during incidents), any service-linked roles, and roles tagged CriticalService. The min_unused_days threshold prevents false positives from seasonal workloads; a role that ran a quarterly batch job 25 days ago won’t generate a finding.

Detection and analysis

IAM Access Analyzer generates two types of findings relevant to this solution. UnusedPermission findings identify roles with permissions that haven’t been exercised within the analysis period. UnusedIAMRole findings identify roles that haven’t been assumed at all. The Lambda function queries both finding types separately because they follow different remediation paths.

The Lambda function auto-detects the analyzer type at startup. When ANALYZER_SCOPE is set to organization, it checks for an ORGANIZATION_UNUSED_ACCESS analyzer first and falls back to ACCOUNT_UNUSED_ACCESS if none exists. If multiple analyzers of the same type exist in the account, the Lambda function selects the first active analyzer returned by the API. To target a specific analyzer, set the ANALYZER_ARN environment variable explicitly. With an organization-level analyzer, findings include roles from all member accounts. The Lambda function extracts the account ID from each finding’s resource ARN (for example, account 111122223333 from arn:aws:iam::111122223333:role/MyRole) and carries that context through the entire pipeline: attribution, remediation, and issue or PR creation all include the originating account.

For UnusedPermission findings, the Lambda function calls GenerateFindingRecommendation to initiate policy generation, then retrieves the IAM Access Analyzer-recommended policy through the GetFindingRecommendation API. This is a key integration point: IAM Access Analyzer provides the right-sized policy with unused permissions removed, so the automation doesn’t need to generate policies itself.

Here’s what a typical finding looks like for one of AnyCompany’s application roles:

{
  "id": "a1b2c3d4-5678-90ab-cdef-example11111",
  "resource": "arn:aws:iam::123456789012:role/AnyCompanyOrderProcessorRole",
  "findingType": "UnusedPermission",
  "analyzedAt": "2026-03-01T00:00:00Z",
  "unusedPermissions": [
    { "action": "s3:PutObject", "lastAccessed": null },
    { "action": "s3:DeleteObject", "lastAccessed": null },
    { "action": "s3:PutBucketPolicy", "lastAccessed": null },
    { "action": "dynamodb:DeleteItem", "lastAccessed": null }
  ],
  "activePermissions": [
    { "action": "s3:GetObject", "lastAccessed": "2026-02-28T14:30:00Z" },
    { "action": "s3:ListBucket", "lastAccessed": "2026-02-28T14:30:00Z" },
    { "action": "dynamodb:Query", "lastAccessed": "2026-02-28T12:00:00Z" }
  ]
}

The OrderProcessorRole has write and delete permissions for Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB, but only uses read operations. The IAM Access Analyzer recommendation removes the four unused actions while preserving the three active ones.

For UnusedIAMRole findings, no recommendation is needed: the role isn’t being assumed at all, so the remediation is to disable or delete it. The Lambda function caps the number of unused role issues per run (configurable using MAX_UNUSED_ROLE_ISSUES, default 10) to avoid overwhelming teams with a flood of issues on the first execution.

Role attribution using CloudTrail

For each finding, the Lambda function queries CloudTrail to determine how the role was created. The CreateRole event contains the information needed to classify the role’s origin.

An IaC-created role looks like this in CloudTrail:

{
  "eventName": "CreateRole",
  "userIdentity": {
    "type": "AWSService",
    "invokedBy": "cloudformation.amazonaws.com"
  },
  "requestParameters": {
    "roleName": "AnyCompanyOrderProcessorRole"
  },
  "userAgent": "cloudformation.amazonaws.com"
}

The cloudformation.amazonaws.com service principal and user agent tell the automation this role was created through a CloudFormation or AWS CDK deployment. The Lambda function then looks up the role’s tags to find the originating repository (stored in a Repository tag set during deployment).

A manually-created role looks different:

{
  "eventName": "CreateRole",
  "userIdentity": {
    "type": "IAMUser",
    "userName": "jstiles"
  },
  "requestParameters": {
    "roleName": "AnyCompanyIncidentResponseRole"
  },
  "userAgent": "console.amazonaws.com"
}

Here, the IAMUser type and console.amazonaws.com user agent indicate someone created this role through the console. Roles created through the AWS CLI show a similar pattern: the IAMUser type with a user agent like aws-cli/2.x.x. The automation classifies both console and AWS CLI-created roles as manually created, because neither has an IaC origin that can be updated programmatically. The automation captures the username and timestamp for the remediation issue.

Cross-account role attribution

When the Lambda function processes findings from an organization-level analyzer, the role might live in a different account than the one running the function. The automation handles this by assuming a cross-account role (configurable using CROSS_ACCOUNT_ROLE_NAME, defaulting to OrganizationAccountAccessRole) in the member account, then querying that account’s CloudTrail and IAM APIs for the CreateRole event. If the cross-account assume fails—because the role doesn’t exist in that account or permissions aren’t configured—the automation falls back gracefully, classifying the role as unknown origin and creating an issue with the account ID and available context. This approach helps the automation produce an actionable output for findings even when attribution is incomplete.

Policy recommendations and AWS CDK code generation

For IaC-managed roles with UnusedPermission findings, the Lambda function retrieves the IAM Access Analyzer-recommended policy and sends it to Amazon Bedrock to generate production-ready AWS CDK code. This is an important distinction: IAM Access Analyzer decides what the policy should be, and Amazon Bedrock wraps that policy in the AWS CDK constructs, imports, and resource definitions that the CI/CD pipeline needs to deploy the update.

The prompt instructs Amazon Bedrock to convert the recommended policy to AWS CDK code exactly as provided, with no modifications:

Generate Python CDK code that creates/updates the role with the
RECOMMENDED policy exactly as provided. Include proper imports
(aws_cdk, aws_iam), use CDK best practices (PolicyStatement,
proper resource ARNs), and add tags: ManagedBy=CDK,
RemediatedBy=AccessAnalyzer.

IAM Access Analyzer generates recommendations for both inline policies and customer managed policies. When a managed policy has partially unused permissions, the recommendation contains the full right-sized policy. The automation wraps this in AWS CDK code as an iam.ManagedPolicy construct. Note that if a managed policy is shared across multiple roles, the recommendation applies to the specific role’s usage pattern. In this case, the automation generates an issue for manual review rather than a PR, because modifying a shared policy could affect other roles.

The generated code goes through a validation step before inclusion in any PR. The Lambda function compiles the Python code to check for syntax errors and verifies that required AWS CDK patterns (iam, PolicyStatement) are present. If validation fails, the finding is logged as an error rather than creating a broken PR.

The solution doesn’t currently invoke the IAM Access Analyzer ValidatePolicy API to check the generated policy for errors or overly permissive statements. However, this is a natural extension point. Teams can add a validation step that calls ValidatePolicy on the Amazon Bedrock-generated policy before including it in a PR, detecting issues like missing resource constraints or invalid action names.

Amazon Bedrock also generates a plain-English explanation of the policy changes. For AnyCompany’s OrderProcessorRole, the explanation might read:

“The role currently has full S3 write access and DynamoDB delete permissions, but only uses read operations. Removing s3:PutObject, s3:DeleteObject, s3:PutBucketPolicy, and dynamodb:DeleteItem reduces the scope of impact if credentials are compromised, while preserving the s3:GetObject, s3:ListBucket, and dynamodb:Query permissions the application needs.”

The solution uses the Anthropic Claude Sonnet model on Amazon Bedrock for CDK code generation (where accuracy matters) and Claude Haiku on Amazon Bedrock for explanations (where speed and cost efficiency matter more).

Three-path remediation

The Lambda function evaluates each finding’s origin and routes it to one of three remediation paths.

Path 1: IaC-managed roles (pull request) – For AnyCompany’s OrderProcessorRole, the automation creates a PR in the originating repository. The PR includes:

  • The Amazon Bedrock-generated AWS CDK code implementing the IAM Access Analyzer-recommended policy
  • A policy diff showing exactly which permissions are being removed
  • The plain-English explanation of what the changes accomplish
  • Labels (security, iam-remediation, automated) for filtering and tracking

The team that owns the role reviews the PR through their normal code review process. Once merged, the fix deploys consistently across environments through the existing CI/CD pipeline.

Path 2: Manually-created roles (issue) – For AnyCompany’s IncidentResponseRole, the automation creates an issue that includes the Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, an Amazon Bedrock-generated explanation, and step-by-step guidance on importing the role into IaC. This gives the team an immediate remediation path (apply the recommended policy) while encouraging long-term governance through IaC adoption.

Path 3: Unused roles (soft-disable issue) – For roles that haven’t been assumed at all, the automation creates an issue recommending a three-stage decommission workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. This controlled approach reduces the risk of removing a role that’s used infrequently or seasonally – if something breaks during the monitoring period, removing the deny-all policy restores access immediately.

Dry-run mode

Before creating real PRs and issues, you can run the automation in dry-run mode by setting “dry_run": true in the CI/CD configuration or setting the CI_CD_PLATFORM environment variable to dryrun. In this mode, the Lambda function processes findings, classifies roles, and generates remediation data, but logs what it would create instead of making actual API calls to your repository platform. You can use the log to validate the automation’s behavior, review the classification accuracy, and tune exclusions before going live.

Operational metrics

The Lambda function publishes CloudWatch metrics after each run:

findings_processed Total UnusedPermission findings evaluated
iac_roles_found Roles classified as IaC-managed
manual_roles_found Roles classified as manually created
unused_roles_found Roles with no assume activity (UnusedIAMRole findings)
prs_created Pull requests created for IaC roles
issues_created Issues created (manual roles and unused roles)
errors Processing errors (failed classifications, API failures)

These metrics feed into dashboards and alarms. AnyCompany sets an alarm on errors > 5 to catch API throttling or configuration issues, and tracks prs_created + issues_created over time to measure remediation velocity.

Implementation

The solution ships as two AWS CDK stacks and deploys in minutes. The accompanying GitHub repository contains the complete source code, AWS CDK stacks, configuration templates, and step-by-step deployment instructions.

At a high level, deployment involves:

  1. Prerequisites: An AWS account with an ACCOUNT_UNUSED_ACCESS or ORGANIZATION_UNUSED_ACCESS analyzer enabled, Python 3.11 or later, AWS CDK v2, a CI/CD platform API token stored in AWS Secrets Manager, and Amazon Bedrock model access for the Anthropic Claude models you plan to use. The model IDs are configurable environment variables (BEDROCK_CODEGEN_MODEL and BEDROCK_EXPLANATION_MODEL); Amazon Bedrock retires older foundation models over time, so if the shipped defaults stop working, set these variables to current models you have enabled and redeploy. The repository README documents this.
  2. Configuration: Two files in the config/ directory control behavior. exclusions.json defines which roles and permissions to skip (break-glass roles, service-linked roles, tagged exceptions), and ci_cd_config.json configures your repository platform integration (GitLab or GitHub), labels, and throttling limits.
  3. Deploy: Run cdk deploy --all to create the Lambda function, EventBridge schedule, IAM roles, and CloudWatch alarms.
  4. Validate in dry-run mode: Start with “dry_run": true to see how the automation classifies your roles without creating real PRs or issues. Review the CloudWatch logs to confirm attribution accuracy and tune exclusions.
  5. Go live: Set “dry_run": false and redeploy. The Lambda function runs on schedule (daily by default) and begins creating PRs and issues.

The repository README covers each step in detail, including organization-wide deployment, cross-account configuration, and platform-specific setup for GitLab and GitHub.

Operational considerations

Deploying the automation is only the starting point. Running it in production means making decisions about how roles are retired, how the volume of findings is managed at scale, which roles warrant human review before any change is proposed, and how you measure the automation’s impact over time. The following practices keep remediation sustainable as your IAM footprint grows, so the automation reduces operational burden rather than adding to it.

Unused role lifecycle

Unused roles follow a three-stage decommission workflow. When the automation identifies a role that hasn’t been assumed within the analysis period, it creates an issue with the recommended decommission steps; the automation doesn’t modify the role directly. The team then follows the soft-disable approach:

  1. Attach a deny-all inline policy to the role. This blocks all actions without deleting the role or its existing policies.
  2. Monitor for 30 days. If a workload depends on the role (seasonal jobs, infrequent batch processes), the deny-all policy surfaces the dependency quickly. Removing the deny-all policy restores full access immediately; no need to recreate the role or reattach policies.
  3. Delete the role after the monitoring period confirms no impact.

This approach is deliberately conservative. Deleting a role is irreversible; you lose the trust policy, attached policies, and any resource-based policies that reference it. The soft-disable step gives teams a safety net while still making progress on reducing their unused role inventory.

Scaling and throttling

On AnyCompany’s first run, the automation found 47 unused permission findings and 4 unused roles. That’s manageable. But organizations with hundreds of accounts and thousands of roles might see significantly more findings on initial deployment.

This is especially true with an organization-level analyzer. A single-account deployment might surface dozens of findings; an organization-level analyzer across multiple accounts could surface hundreds or thousands on the first run. The throttling controls become critical at this scale.

Two throttling controls prevent the automation from overwhelming teams:

  • max_findings_per_run (default 50): Caps the total UnusedPermission findings processed per Lambda function execution. Remaining findings are picked up on the next scheduled run.
  • MAX_UNUSED_ROLE_ISSUES (default 10): Caps unused role issues per run. This is especially important during initial deployment when you might have a large backlog of roles that haven’t been assumed in months.

Start with conservative limits and increase them as your team builds confidence in the review process. A team that can review 10 PRs per week shouldn’t receive 50 on Monday morning.

Approval workflows for sensitive roles

Not every role should receive automated PRs. Roles with administrative permissions or access to sensitive data might warrant manual review before any remediation is created. The exclusion configuration supports this through the approval_required_for_tags field:

{
  "approval_required_for_tags": {
    "Sensitive": ["true"],
    "Admin": ["true"]
  }
}

Roles matching these tags generate issues for manual review instead of automated PRs, regardless of whether they’re IaC-managed. This gives security teams a checkpoint for high-risk roles while still automating remediation for standard application roles.

Monitoring and alerting

The metrics published after each Lambda function run (covered in the Technical details section) feed into CloudWatch dashboards and alarms. A few patterns worth setting up:

  • Alert on errors > 5 per run to catch API throttling, expired CI/CD tokens, or Amazon Bedrock availability issues.
  • Track prs_created + issues_created over time. A healthy trend shows this number decreasing as your environment converges toward least privilege.
  • Monitor unused_roles_found as a leading indicator. A sudden increase might signal a team spinning up roles for a project and not cleaning up afterward.
  • Compare iac_roles_found to manual_roles_found over time. As teams adopt IaC, the ratio should shift toward IaC-managed roles, which means more automated remediation and less manual work.

Cost

The solution uses Lambda (minimal cost at daily execution), CloudTrail (typically already enabled), IAM Access Analyzer (charges per IAM role or user analyzed per month for the unused access analyzer), and Amazon Bedrock (pay-per-token for AWS CDK code generation and explanations). For most organizations the ongoing cost is low, and Amazon Bedrock token usage is the largest variable, scaling with the number of findings processed per day and the complexity of each policy. Review the pricing pages for each service for current rates.

For organization-level deployments, the IAM Access Analyzer cost scales with the number of IAM roles analyzed across all member accounts. The ORGANIZATION_UNUSED_ACCESS analyzer charges per role per month across the organization, so an organization with 500 roles across 20 accounts will see higher analyzer costs than a single account with 50 roles. Review the IAM Access Analyzer pricing page for current rates.

Cleanup

To remove the solution, run cdk destroy --all from the infrastructure/ directory. This removes the Lambda function, EventBridge rule, CloudWatch alarms, and IAM roles created by the stacks.

If you stored a CI/CD platform API token in Secrets Manager as part of deployment, delete it with aws secretsmanager delete-secret --secret-id <your-secret-name> --recovery-window-in-days 7. The 7-day recovery window lets you restore the secret if the deletion was accidental. After 7 days, the secret is permanently deleted and can’t be recovered. To delete immediately without a recovery window, add --force-delete-without-recovery.

Lambda automatically creates a CloudWatch Logs log group at /aws/lambda/<function-name> that persists after cdk destroy --all and continues to incur log storage charges. To remove it, run aws logs delete-log-group --log-group-name /aws/lambda/<function-name>. WARNING: This permanently deletes all execution logs.

The IAM Access Analyzer isn’t created by the AWS CDK stacks. WARNING: Deleting the analyzer permanently removes all findings, analysis history, and unused permission data. Export any findings you need to retain before deletion. After exporting, run aws accessanalyzer delete-analyzer --analyzer-name <your-analyzer-name> to delete it. The ACCOUNT_UNUSED_ACCESS and ORGANIZATION_UNUSED_ACCESS analyzer types incur charges based on the number of IAM roles and users analyzed per month.

If you deployed in organization mode and created cross-account roles (default name: OrganizationAccountAccessRole) in member accounts solely for this solution, remove them from those accounts.

Any PRs or issues already created in your CI/CD platform remain after stack deletion; they’re artifacts in your repository, not AWS resources. See the repository README for detailed cleanup instructions.,

Conclusion

Automating IAM permission remediation turns least privilege from a periodic compliance exercise into an operational practice. By connecting IAM Access Analyzer findings and recommendations to your CI/CD pipeline, remediation shifts from manual security tasks to code review processes that your teams already follow.

The three-path strategy acknowledges how infrastructure evolves. IaC-managed roles receive pull requests with production-ready AWS CDK code and plain-English explanations. Manually created roles receive actionable issues with recommended policies and IaC migration guidance. Unused roles are put on a controlled decommission path that protects against accidental disruption. Over time, the manual role count decreases as teams adopt IaC, and remediation becomes a routine part of your deployment pipeline.

Start with a pilot. Choose 10–20 non-production roles, deploy in dry-run mode, and review the classification results. Tune your exclusions, confirm the CloudTrail attribution is accurate for your environment, and then enable live remediation. Expand to production roles after your team is comfortable with the review cadence.

When you’re ready to scale beyond a single account, switch to an organization-level analyzer and the same Lambda function will process findings across all member accounts with no architectural changes required, only a configuration toggle.

The complete source code, AWS CDK stacks, and configuration templates are available in the accompanying GitHub repository.

If you have feedback about this post, submit comments in the Comments section below.
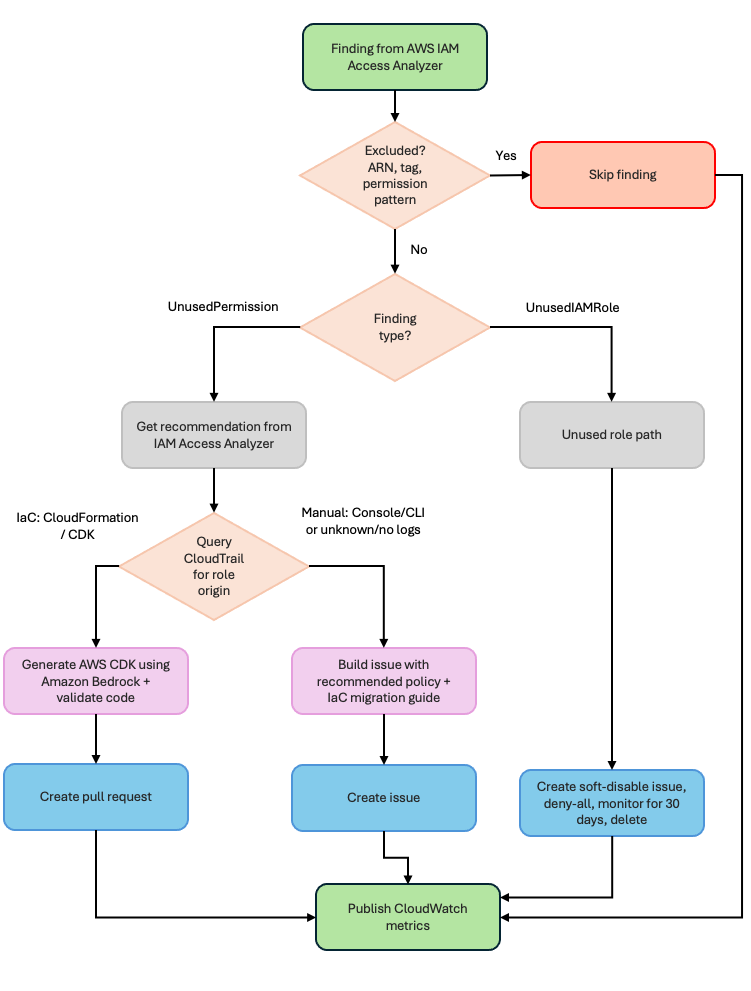

Luis Pastor

Luis E Pastor

Luis is a Senior Security Solutions Architect at AWS specializing in infrastructure security, compliance, and generative AI security. He leads technical field communities focused on security and compliance while contributing to AWS Well-Architected Framework guidance. Before AWS, he helped clients across financial services, healthcare, and retail industries improve their security posture in hybrid environments. Outside of work, Luis enjoys staying active and culinary adventures.

Rodolfo Brenes

Rodolfo Brenes

Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solution Architect who specializes in Identity and Security in AWS. Her entire career has been focused on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and experiencing new cultures and food.

Satish Uppalapati

Satish is an Associate Assurance Consultant with AWS Security Assurance Services (SAS) and has more than 8 years of experience in IT risk, governance, and regulatory assurance. He works with AWS customers to align cloud environments with multiple frameworks. Satish helps organizations build security and governance programs that meet regulatory objectives while supporting business operations. He also focuses on advancing governance for AI systems, including emerging standards.

Extend your data perimeter to the AWS Management Console with Private Access

Post Syndicated from Madhur Kulkarni original https://aws.amazon.com/blogs/security/extend-your-data-perimeter-to-the-aws-management-console-with-private-access/

Organizations in regulated industries such as financial services, government, defense, and healthcare restrict their sensitive workloads to isolated network environments with no access to the public internet. Until now, customers could restrict AWS Management Console access to authorized AWS accounts and corporate networks, but the console itself required internet connectivity. This was creating tension between operational convenience and network security controls.

We’re happy to announce that AWS Management Console Private Access is now generally available with support for virtual private clouds (VPCs) without internet connectivity. Organizations in regulated industries that restrict workloads to isolated network environments can now route all traffic for supported service consoles—including authentication flows, static assets (JavaScript, CSS, images), console-only APIs, and AWS service API calls—through AWS PrivateLink VPC endpoints, eliminating the need for an internet gateway, NAT gateway, or any route to the public internet. This capability is available in all AWS commercial Regions for a select set of supported service consoles.

In 2023, we launched AWS Management Console Private Access, which you can use to connect to the console by routing console, sign-in, and service API calls through VPC endpoints. However, accessing the console required internet connectivity for static assets and console-only APIs. This meant security teams faced a choice: allow internet connectivity to use the console or deny console access to operators working in network-isolated environments.

With this launch, AWS Management Console Private Access addresses two common scenarios:

  • Console traffic over internet restricted networks: Traffic for supported service consoles now flows entirely through your VPC endpoints—no proxy allowlists to maintain, no TLS-intercepting proxies to operate, and no CLI-only workflows to accept as a compromise. The same path works seamlessly from Amazon WorkSpaces, Amazon Elastic Compute Cloud (Amazon EC2) instances, and on-premises networks connected through AWS Direct Connect or AWS Site-to-Site VPN. Combined with sign-in resource control policies (RCPs) and sign-in resource policies, you can ensure that console authentication only succeeds from expected networks—even if valid credentials are presented elsewhere, the session is denied. Teams that previously relied on restricted egress rules or manual domain allowlists now get full console access with the same network controls they already trust.
  • Data-exfiltration prevention: Private Access enables you to restrict which AWS accounts and organizational identities can use the AWS Management Console from within your VPC. This prevents access from personal accounts and from accounts outside your organization. Attach a VPC endpoint policy with an aws:ResourceOrgID condition, and console actions are automatically scoped to resources inside your organization. Sign-in RCPs add a second layer by ensuring authentication only succeeds from networks within your perimeter. Together, these controls prevent supported service consoles from being used to access resources in accounts outside your organization—such as personal accounts—without requiring complex network-layer workarounds.

In this post, you will learn how AWS Management Console Private Access works in environments without internet connectivity, and how to layer access controls using VPC endpoint policies and sign-in resource control policies (RCPs) to strengthen your data perimeter.

Solution overview

AWS Management Console Private Access and sign-in resource control policies are a natural extension of the service control policies (SCPs), resource control policies, and VPC endpoint policies you already use for API traffic; now applied to the console session itself. The same data perimeter controls for identity, resource, and network that protect your programmatic access now protect interactive browser sessions too.

Perimeter Control objective Policy construct Implementation Steps
Identity Only trusted identities can access my resources Sign-In RCPs and RBPs Restrict which principals can sign in to the console. Before authentication, signin:PrincipalArn is available for exemptions only. After authentication, RCPs restrict at the organization, account, or principal level (aws:PrincipalOrgID, aws:PrincipalAccount, aws:PrincipalArn); RBPs restrict at the account or principal level.
Identity Only trusted identities are allowed from my network Console VPC endpoint policy and Sign-In VPC endpoint policy Console endpoint: aws:PrincipalOrgID or aws:PrincipalAccount on signed-in identities. Sign-In endpoint: aws:ResourceOrgID or aws:ResourceAccount before authentication, principal and resource keys after authentication. Blocks sign-in to accounts outside your organization, such as personal accounts, from your network.
Resource My identities can access only trusted resources SCP Resource perimeter SCP with aws:ResourceOrgID follows your principals into every console session; each service API call the console makes on their behalf is denied if the target resource is outside your organization.
Resource Only trusted resources can be accessed from my network Console VPC endpoint policy and service VPC endpoint policies Console endpoint policy with aws:ResourceOrgID and aws:ResourceAccount scopes what the console can reach through your network.
Network My identities can access resources only from expected networks SCP Network perimeter SCPs that use aws:SourceVpc deny your principals’ service calls from outside expected networks. With Private Access, requests proxied by the console to supported services carry aws:SourceVpc set to the VPC hosting your Private Access endpoints. Direct browser requests carry VPC context only when the service has its own VPC endpoint, so configure endpoints for every service you use. AWS recommends conditioning on aws:SourceVpc rather than specific aws:SourceVpce values.
Network My resources can only be accessed from expected networks Sign-In RBPs and RCPs and network perimeter RCPs Sign-In policies deny console authentication from unexpected networks using aws:SourceIp, aws:SourceVpc, aws:SourceVpce, and aws:VpcSourceIp in both pre-authentication and post-authentication statements. Network perimeter RCPs apply the same network conditions to your data resources for any access path.

With this launch, Console Private Access routes browser traffic for supported service consoles through VPC endpoints, including:

  • Authentication flows – Sign-in, credential exchange, and session token requests
  • Static assets – JavaScript, CSS, and images that render the console UI
  • Service console API calls – The backend requests made when users interact with service consoles

How traffic flows from a workload in a private VPC through the three Private Access endpoints, with no path to the public internet (shown in Figure 1):

  1. The operator’s browser requests <region>.console.aws.amazon.com.
  2. The corporate DNS forwarder forwards the query to an Amazon Route 53 Resolver inbound endpoint configured within the VPC, which forwards the traffic to the console VPC endpoint.
  3. Browser traffic flows from on-premises through Direct Connect (or AWS Site-to-Site VPN) to the VPC, and the VPC endpoint routes traffic to the console service over the AWS private network.
  4. The console service redirects to the SignIn endpoint <region>.signin.aws.amazon.com to establish a browser session.
  5. The DNS now resolves to the SignIn VPC endpoint’s private IP addresses, and browser traffic flows to the SignIn service over the AWS private network.
  6. After entering credentials, the SignIn service evaluates VPC endpoint policies, in addition to resource-based policies (RBPs) and RCPs, then redirects back to the console.
  7. The console evaluates VPC endpoint policies, loads static content from the console API VPC endpoint, and enforces identity and resource restrictions when making calls to AWS service APIs.
  8. Users can now access the AWS Management Console over Private Access.
Figure 1: Network isolation architecture

Figure 1: Network isolation architecture

Deploy a pilot of AWS Management Console Private Access

This high-level walkthrough sets up AWS Management Console Private Access for a single AWS Region within one organizational unit (OU). We recommend rolling out incrementally; validate each step before you expand to additional Regions and OUs.

If you want to validate the mechanics of a Private Access deployment before you build out the full solution, the Getting started with a test environment guide walks you through a minimal configuration: a single VPC with the three Private Access endpoints and a permissive policy. This gives you a working setup to experiment with, independent of the deployment described in the rest of this post. To understand how sign-in policies can verify a user’s network location when they access the console, see Controlling console access with resource-based policies and resource control policies.

Prerequisites

You must have the following prerequisites:

Step 1: Baseline current console access

Before changing anything, use CloudTrail to map how your users access the console today. Search for eventName = ConsoleLogin over a representative window (we recommend 30 days) and review the sourceIPAddress, vpcEndpointId, and awsRegion fields. Identify which identity types are in use: root user, IAM user, SAML federation, and AWS IAM Identity Center. Decide which OU or account you will pilot with.

Note: A misconfigured sign-in policy can lock users out of the console. Avoid piloting in a production or shared account. Instead, use a dedicated test account and configure a break-glass principal (covered in Step 5) before enabling access enforcement.

Step 2: Create the Private Access VPC endpoints

In your chosen Region, create or identify a VPC to host the endpoints, then create three interface VPC endpoints in that VPC:

  • com.amazonaws.<region>.console for the console.
  • com.amazonaws.<region>.signin for AWS Sign-In.
  • com.amazonaws.<region>.console-static for console-only APIs. This endpoint is required only if your VPC has no internet path.

Step 3: Configure private DNS for AWS Management Console Private Access

To use AWS Management Console Private Access, you must configure private DNS so that the console domains—.console.aws.amazon.com, .signin.aws.amazon.com, and the associated static-content domains—resolve to your interface endpoints’ network interfaces within your VPC.

  • For workloads inside your VPC: If the workloads in your VPC use the default Amazon Route 53 Resolver, no additional DNS configuration is required. When you create each interface endpoint, enable the private DNS name option (set PrivateDnsEnabled = true). The public console domains will then resolve automatically to the endpoint network interfaces inside your VPC. If you use a custom DNS resolver or a private hosted zone, you must configure it explicitly to map the console domains to the endpoint addresses. See Working with private hosted zones for more information. For the complete list of domains and detailed DNS configuration steps, see the AWS Management Console Private Access required endpoints documentation.
  • For workloads outside your VPC: For workloads that reach the endpoints from outside the VPC—such as corporate offices connecting over AWS Direct Connect or AWS Site-to-Site VPN—ensure that your corporate DNS resolver returns the endpoint addresses for these domains. See Simplify DNS management in a multi-account environment with Route 53 Resolver for more information.

Step 4: Verify private connectivity

Sign in to the console from a workload inside your VPC. The console should load normally. To confirm that traffic is routing through your VPC endpoints, look for the lock icon in the console navigation bar, shown in Figure 2.

Figure 2: Console Private Access

Figure 2: Console Private Access

You can also verify in CloudTrail that recent ConsoleLogin events show the vpcEndpointId field populated with one of your endpoint IDs. Here’s an example CloudTrail ConsoleLogin event snippet showing the vpcEndpointId field:

{
  "eventVersion": "1.08",
  "userIdentity": {
    "type": "AssumedRole",
    "principalId": "AROA3XFRBF23EXAMPLE:john.doe",
    "arn": "arn:aws:sts::123456789012:assumed-role/Admin/john.doe",
    "accountId": "123456789012"
  },
  "eventTime": "2026-07-08T19:15:32Z",
  "eventSource": "signin.amazonaws.com",
  "eventName": "ConsoleLogin",
  "awsRegion": "us-east-1",
  "sourceIPAddress": "10.0.1.47",
  "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7)...",
  "requestParameters": null,
  "responseElements": {
    "ConsoleLogin": "Success"
  },
  "additionalEventData": {
    "LoginTo": "https://console.aws.amazon.com/console/home",
    "MobileVersion": "No",
    "MFAUsed": "Yes",
    "vpcEndpointId": "vpce-0abc123def456789a"
  },
  "eventID": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111",
  "eventType": "AwsConsoleSignIn",
  "recipientAccountId": "123456789012"
}

If the AWS Management Console doesn’t load, work through the following checks.

Private DNS is enabled on each interface endpoint (or your custom resolver returns the endpoint addresses)

When Private DNS is enabled, AWS automatically creates the DNS entries that resolve the service domains (such as console.aws.amazon.com) to the private IP addresses of your VPC endpoints. Without it, your browser still routes to the public AWS endpoints, bypassing your private access setup entirely.

  1. Confirm that each endpoint shows PrivateDnsEnabled:
    aws ec2 describe-vpc-endpoints \
    --filters "Name=vpc-endpoint-type,Values=Interface" \
    --query "VpcEndpoints[].{Id:VpcEndpointId,Service:ServiceName,PrivateDns:PrivateDnsEnabled}" \
    --output table
    

  2. Then, from within your VPC, verify that the domains resolve to private addresses:
    nslookup console.aws.amazon.com
    nslookup signin.aws.amazon.com
    
    # Should return a private IP (e.g., 10.x.x.x), not a public one
    

Each query should return a private IP address from your VPC CIDR range. If you use a custom DNS resolver instead of the Amazon-provided DNS, ensure your forwarding rules direct the AWS domain queries to the Route 53 Resolver inbound endpoints in your VPC.

The endpoint security groups allow HTTPS (TCP 443) from your workload subnets

Each VPC endpoint creates elastic network interfaces (ENIs) in your subnets, and these ENIs are governed by security groups. If those security groups don’t permit inbound HTTPS traffic from your workloads, the connection fails silently.

  1. Identify the security groups attached to your endpoints:
    aws ec2 describe-vpc-endpoints --vpc-endpoint-ids vpce-0abc123def456789a \
      --query "VpcEndpoints[].Groups[].GroupId" --output text
    

  2. Then verify that each security group allows inbound TCP 443 from your workload subnets:
    aws ec2 describe-security-groups --group-ids sg-xxxxxxxx \
      --query "SecurityGroups[].IpPermissions[?ToPort==\`443\`]" \
      --output json
    

For traffic from outside the VPC (Direct Connect or Site-to-Site VPN), corporate DNS returns the endpoint IPs and the route propagates correctly

If you access the console from an on-premises workstation connected over AWS Direct Connect or AWS Site-to-Site VPN, two additional conditions must be met.

  1. Your corporate DNS must resolve the AWS domains to the VPC endpoint private IPs. From your on-premises machine, run:

    nslookup console.aws.amazon.com

    If this returns public AWS IPs, your corporate DNS isn’t forwarding queries through Route 53 Resolver. Configure conditional forwarding for the aws.amazon.com and amazonaws.com domains to your Resolver inbound endpoint IPs.

  2. Second, network routes must propagate correctly. Ensure the route table associated with your endpoint subnets has propagated routes from your virtual private gateway (VGW) or transit gateway, so return traffic can reach your on-premises network. Verify this with:
    aws ec2 describe-route-tables \
      --filters "Name=association.subnet-id,Values=subnet-xxxxx" \
      --query "RouteTables[].PropagatingVgws"
    

A quick end-to-end validation: Run traceroute console.aws.amazon.com from your workstation and confirm the path uses private hops only—no traffic should traverse the public internet.

If the console loads but the lock icon is missing

If the console loads but the connection isn’t private (for example, the lock icon is missing), the browser is reaching the console over the public internet instead of through your VPC endpoints.

  • Run nslookup console.aws.amazon.com from a workload inside the VPC. The result should be a private IP from your VPC CIDR range. A public IP means DNS is bypassing the endpoint, which usually happens because Private DNS has not been enabled on the interface endpoint (set PrivateDnsEnabled = true).
  • For workloads outside the VPC, make sure your corporate DNS forwards the console domains into the VPC, for example, through an Amazon Route 53 Resolver inbound endpoint.

Step 5: Apply VPC endpoint policies

Attach an endpoint policy to the console and AWS Sign-In endpoints that limits access to identities in your organization. The static-content endpoint doesn’t support endpoint policies.

Begin with a permissive Allow * policy and confirm that traffic routes through the endpoints (you should see the vpcEndpointId field populated in CloudTrail console events). After confirming the routing, add restrictions to your VPC endpoint policy and observe the traffic.

A starter policy uses two condition keys: aws:PrincipalOrgID to restrict identities to your organization and aws:ResourceOrgID to restrict the resources the console can reach to your organization’s resources. The full reference, including additional condition keys and resource-restriction patterns, is in the AWS Management Console Private Access user guide.

For policies beyond the pilot, see Data perimeters on AWS. The data perimeter policy examples GitHub repository covers service-specific considerations for implementing data perimeters in your environment.

Step 6: Apply a Sign-In policy

Sign-In policies deny console authentication requests that don’t match your network or principal conditions. The policy is composed of a pre-authentication statement covering signin:Authenticate and a post-authentication statement covering signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token. Include both statements.

For your pilot, deploy the policy as an RCP from your AWS Organizations management account. When enabled, the RCP applies to all accounts in your organization, so we recommend piloting in a dedicated test organization before rolling it out broadly. Activate enforcement by calling the signin:PutConsoleAuthorizationConfiguration API for the organization in the us-east-1 Region (AWS Sign-In replicates policies globally from there). Resource permission statements have no effect until console authorization is enabled.

Important: Configure at least one excluded principal as a break-glass path before you enable the RCP. The recommended principal is a dedicated IAM role.

  1. Write the permission statements that define the network conditions:
    Example – Restrict access to corporate VPC:

    aws signin put-resource-permission-statement \
      --source-vpc vpc-0abc123def456789 \
      --requested-region us-west-2 \
      --excluded-principal "arn:aws:iam::123456789012:user/EmergencyAdmin" \
      --region us-east-1
    

    Example – Restrict access to specific IP range:

    aws signin put-resource-permission-statement \
      --source-ip "IP_ADDRESS" \
      --excluded-principal "arn:aws:iam::123456789012:role/BreakGlassRole" \
      --region us-east-1
    

  2. Enable console authorization for the organization to start enforcing the policy.
    aws signin put-console-authorization-configuration \
      --target-id <your-target-id> \
      --region us-east-1
    

  3. Review the consolidated policy that’s now in effect: 
    aws signin get-resource-policy --region us-east-1
    

For policy examples, the AWS Command Line Interface (AWS CLI) reference, and the lockout-recovery procedure, see the sign-in RBP blog post and the Controlling console access with resource-based policies documentation. The same documentation also covers the per-account alternative, which uses an RBP attached to a single account instead of an organization-wide RCP.

Step 7: Add a service VPC endpoint

So far, the console shell loads, the lock icon appears, and your Sign-In policy lets approved identities through. If you sign in to a service console such as the AWS Key Management Service (AWS KMS) console, the page might fail to load resources or hang. The Private Access endpoints carry the console shell, not the service API calls that the console makes on your behalf. In a VPC without an internet gateway, those calls have nowhere to go.

Add a VPC endpoint for the service itself. For the pilot, create an AWS KMS interface endpoint (com.amazonaws.<region>.kms) in the same VPC, with Private DNS enabled. Open the AWS KMS console from inside the VPC and confirm the list of keys loads. Repeat for each service your users need on day one. Please note that a single service console often calls more than one AWS service API. If a console loads but parts of the page show errors or stay empty, the most common cause is a missing endpoint for one of the services it depends on.

The current list of services that support PrivateLink is in the AWS PrivateLink documentation. Service consoles whose services don’t support PrivateLink will not work in a no-internet VPC and need to be handled separately.

Step 8: Hide Regions and services you haven’t configured (optional)

Console links to a service or Region that you don’t have endpoints for will fail inside your VPC. To prevent users from navigating to broken pages, use User Experience Customization (UXC) to hide Regions and services that aren’t part of your Private Access deployment. UXC is configured at the account level and applies to navigation, search results, and service-selection drop-downs.

Step 9: Validate, then expand

After applying the endpoint policies and the Sign-In RCP to one pilot account:

  1. Sign in from inside the corporate network. The session should succeed.
  2. Sign in from outside the corporate network. The session should be denied at the Sign-In step, before reaching the console.
  3. In CloudTrail, confirm ConsoleLogin events show vpcEndpointId populated for traffic from inside the network.
  4. For unexpected denials, look in CloudTrail for ConsoleLogin events with the error message Authorization denied because of a resource-based policy or Authorization denied because of a resource control policy to identify which statement was responsible.

Considerations

A few items worth mentioning before you commit to this design:

  • AWS IAM Identity Center: IAM Identity Center sign-in support isn’t yet available through a VPC endpoint. Initial single sign-on (SSO) authentication must still transit over the internet.
  • Programmatic access: Sign-In RBPs and RCPs gate interactive console sign-in. AWS SDK and AWS CLI requests signed with SigV4 aren’t affected. This is also your recovery path: a principal with signin:DeleteConsoleAuthorizationConfiguration permission can disable enforcement programmatically if console authorization is misconfigured.
  • Apps integrated with AWS Sign-In: Sign-In policies also apply to Amazon Connect, Amazon WorkSpaces, Amazon QuickSight, AWS Health Dashboard, Amazon AppStream 2.0, and Amazon Lightsail when those applications use AWS Sign-In to authenticate.
  • AWS Management Console Private Access is available in all commercial AWS Regions but supports only a subset of AWS service consoles. See Supported AWS Regions, service consoles, and features in Private Access documentation for more information.
  • For services that aren’t supported, you can still navigate to other consoles, but will require internet connectivity for the unsupported service consoles and console-only APIs.
  • Costs: You pay regular AWS PrivateLink endpoint pricing and data processing for each endpoint and each Region you deploy in. The three Private Access endpoints (console, signin, and console-static) plus the service endpoints you already use are the relevant line items.

Conclusion

In this post, we showed you how to extend the AWS data perimeter framework to the AWS Management Console. You routed console traffic through VPC endpoints with AWS Management Console Private Access, restricted console sign-in by network and organization with Sign-In RBPs and RCPs, and configured the console to operate in a VPC without an internet gateway. The four control objectives that you already enforce for API traffic now also apply to the console.

To get started, see the AWS Management Console Private Access documentation. For deployment patterns and Region-by-Region considerations, see the AWS Management Console Private Access reference architectures. For background on the broader pattern, see Establishing a data perimeter on AWS.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the IAM forum on AWS re:Post or contact AWS Support.

Madhur Kulkarni

Madhur Kulkarni

Madhur is a Sr. Customer Solutions Manager at AWS, working with Strategic Accounts customers to accelerate cloud adoption and drive business outcomes. He partners with cross-functional teams across customer engineering, AWS service teams, and specialists organizations to deliver enterprise-scale cloud solutions.

Mateusz Jaworski

Mateusz Jaworski

Mateusz is a Principal Engineer at AWS, where he works on AWS Management Console.

Sujay Ghosh

Sujay Ghosh

Sujay is a Software Development Manager at AWS, where he leads a team responsible for enabling secure, reliable access to the AWS Management Console. He is passionate about building scalable infrastructure that helps millions of customers manage their cloud resources safely and efficiently.

Abhijit Barde

Abhijit Barde

Abhijit is a Principal Product Manager at AWS, where he focuses on making it straightforward for all AWS users to discover, monitor, and operate their AWS infrastructure using conversational assistants and generative AI.

Enforce zero data retention on Amazon Bedrock with Bedrock Projects and service control policies

Post Syndicated from Rob Higareda original https://aws.amazon.com/blogs/security/enforce-zero-data-retention-on-amazon-bedrock-with-bedrock-projects-and-service-control-policies/

With the introduction of models that require data sharing with third-party providers—such as Claude Fable 5—organizations need a way to centrally enforce data retention policies. Amazon Bedrock gives you control over whether your prompts and model outputs are retained after an inference request completes. You might need a way to enforce your retention settings across all accounts and have granular control of project data retention when compatible with the selected model.

In this blog post, I walk you through how Amazon Bedrock data retention modes work, the tools available for managing retention—including Amazon Bedrock Projects and service control policies (SCPs)—and how to verify your policy settings are working correctly.

In this post, you will learn:

  • How Amazon Bedrock data retention modes work and what each mode means for your data
  • How to use Amazon Bedrock Projects with compatible models to isolate workloads with different retention needs
  • How to write and deploy an SCP that prevents anyone in your organization from enabling data sharing
  • How data retention modes interact with cross-Region inference profiles
  • How to verify your configuration is working correctly

Understanding data retention modes

You can use Amazon Bedrock to control data retention through a mode setting on your account. This determines what happens to your prompts and outputs after each inference request, which is important to understand as you assess your compliance needs. Not all models require data retention or data sharing, and you might continue to use Amazon Bedrock with models that don’t require data retention or data sharing. See the Amazon Bedrock documentation for the current list of models that require data retention or data sharing. Ultimately, it’s your responsibility as the customer to select models that align with your compliance needs.

The following modes govern how Amazon Bedrock handles your data:

Mode Behavior Data shared with provider
none Zero data retention. Prompts and responses are processed and immediately discarded. No
default No data is shared with model providers. Some models might require data retention for trust and safety checks for up to 30 days. Consult the model’s terms for specifics. This mode also allows APIs that inherently require retention (for example, Batch API, Responses API with store=true). Models that support zero retention will still operate with zero retention. No
inherit No explicit setting applied, defers to the next higher scope (project defers to account defers to service default). This is the default for new accounts. No
provider_data_share Data is shared with the model provider and retained for up to 30 days for trust and safety. Yes

Understanding mode as a ceiling, not a floor

The most important concept to understand: your configured mode is the upper limit of retention you’re willing to accept; it is not what every request will use. Setting your account to provider_data_share doesn’t mean all your requests suddenly start retaining and sharing data. Models that support zero data retention will still operate with zero retention regardless of your account-level setting.

Think of it as a permissions ceiling:

Your account mode Model you invoke What happens
provider_data_share Claude Sonnet (supports none) Zero retention, Sonnet doesn’t require data sharing or data retention
provider_data_share Claude Fable 5 (requires provider_data_share) Data retained for up to 30 days and might be shared with provider, Fable 5 requires data sharing and data retention
none Claude Sonnet (supports none) Zero retention, no data sharing
none Claude Fable 5 (requires provider_data_share) Blocked, your ceiling is below what the model requires, calls to this model will be denied
default Claude Sonnet (supports none) Zero retention, Sonnet supports it, no data retention or data sharing
default A model requiring retention for safety checks Data is retained, model requires it and your ceiling allows it

Key takeaway: Your mode setting declares the maximum level of data retention you will accept. Models that support zero retention will continue to operate that way regardless of your account setting. Amazon Bedrock is designed so that you do not get more retention than necessary just because your account mode allows it.

Important: provider_data_share isn’t inherited from a model—it’s an explicit opt-in at the account or project level. If your account is set to inherit or default, no model will trigger provider data sharing unless you configure it within your account or project.

Note on inherit behavior: The inherit mode defers to the next scope up in the hierarchy (project defers to account defers to service default). If a project is set to inherit and the account above it is set to provider_data_share, the project will inherit provider_data_share. You will not inherit provider_data_share from a model—that requires an explicit setting at the account or project level.

Note on APIs that require retention: Some Amazon Bedrock APIs require data retention to function regardless of model support, for example, the Batch API and the Responses API with store=true. Setting your mode to none will block these APIs. This is expected behavior: your ceiling of none means you require no retention, so APIs that can’t operate without retention are unavailable.

Why does provider_data_share exist?

Some foundation models require the provider_data_share mode to function. As AI models evolve, so must the mechanism to protect customers and the safety of their use. Models that require provider_data_share have allowed_modes: ["provider_data_share"], meaning they will appear as unavailable unless the account has explicitly opted in. This is by design: AWS requires you to make a conscious decision to share data before you as a customer can use these models. See the current list of models available through Amazon Bedrock and their retention requirements, which can change as new models are released.

If your regulatory requirements, internal policies, or customer commitments prohibit data sharing with third-party model providers, you can enforce this at multiple levels. Amazon Bedrock provides several tools for managing data retention, from fine-grained project-level settings to organization-wide enforcement.

Tools for managing data retention

Amazon Bedrock gives you multiple layers of control over data retention. You can use them independently or combine them for defense-in-depth:

Tool Scope Use case
Amazon Bedrock console Per-account, per-AWS Region Quick configuration and visibility; view and change your retention mode directly in the AWS Management Console.
Amazon Bedrock Projects Per-project within an account Isolate workloads with different retention needs within the same account for compatible models
SCPs Organization-wide Use to prevent any account from opting in to data sharing
IAM policies Per-account or per-principal Fine-grained control, including the management account (which SCPs don’t cover)

Using Amazon Bedrock Projects for granular control

Not every workload in an account has the same data retention requirements. If you’re using the bedrock-mantle endpoint (OpenAI-compatible APIs), you can use Amazon Bedrock Projects to isolate traffic that can accept data retention from traffic that must not be retained—even within the same account.

For example, you might have:

  • A research project where your team needs access to the latest models (including those requiring provider_data_share) for experimentation
  • A production project handling customer data where zero retention is mandatory

With Amazon Bedrock Projects, you can set provider_data_share on the research project while keeping the production project locked to none. Each project enforces its own retention ceiling independently.

How project-level retention works:

  • Each project can have its own data retention mode setting.
  • A project set to inherit will inherit its mode from the account level.
  • A project set to none enforces zero retention regardless of the account setting. Traffic routed through that project can’t trigger data sharing.
  • A project set to provider_data_share allows models requiring data sharing, but only for requests within that project.

This gives organizations the flexibility to adopt new models incrementally while maintaining strict data governance on sensitive workloads. You can manage project settings using the Amazon Bedrock console or the bedrock-mantle API.

Important: Amazon Bedrock Projects are only available on the bedrock-mantle endpoint. They work with models accessed using the OpenAI-compatible APIs (Responses, Chat Completions) and the Anthropic Messages API on the mantle endpoint. Not all models are available on bedrock-mantle; check the endpoint availability by models page for current support.

Workload isolation on the bedrock-runtime endpoint

If you’re using the bedrock-runtime endpoint (Invoke, Converse APIs), project-level data retention isn’t available. The account-level retention mode applies to all requests made through bedrock-runtime.

To achieve workload-level isolation on bedrock-runtime, use separate AWS accounts:

  • Place workloads that need provider_data_share in one account (or OU) without the SCP
  • Place workloads that require zero retention in a separate account (or OU) with the SCP applied

You can use AWS Organizations OUs to group accounts by retention policy and apply SCPs selectively:

Organization Root
├── OU: Zero-Retention (SCP attached — blocks provider_data_share)
│   ├── Account: Production-App-A
│   └── Account: Production-App-B
└── OU: Research (no SCP — allows provider_data_share)
    └── Account: ML-Experimentation

Combining projects with SCPs: If you use an SCP to enforce none at the organization level, it overrides all project-level settings on bedrock-mantle. For accounts where you want project-level flexibility, don’t apply the SCP—use project-level isolation instead. For accounts that must never have data sharing under any circumstances, the SCP provides an unbypassable guarantee across both endpoints.

Using SCPs for organization-wide enforcement

For organizations that need an absolute guarantee that no account can enable data sharing—regardless of who has admin access or which endpoint they use—SCPs provide the strongest enforcement mechanism. SCPs apply to both the Amazon Bedrock control plane (bedrock:PutAccountDataRetention) and the mantle endpoint (bedrock-mantle:PutAccountDataRetention, bedrock-mantle:CreateProject, bedrock-mantle:UpdateProject).

Enforcing zero data retention with an SCP

In this section, I cover how you can use SCPs to manage your data retention policy. I introduce what an SCP is and provide some policies that you can use in your organization.

What is an SCP?

A service control policy (SCP) is a guardrail set at the organization level. It overrides every principal in the organization, including account administrators and root users. Even if someone has full admin permissions, an SCP deny can’t be overridden by an AWS Identity and Access Management (IAM) policy.

SCPs are managed in AWS Organizations and can be attached at different levels:

  • Root – Applies to every account in the organization
  • Organizational unit (OU) – Applies to all accounts in that OU
  • Individual account – Applies only to that specific account

Important: The SCP must be attached to the root OU to cover all accounts. If attached to a child OU, accounts outside that OU will not be protected. Organization admin accounts don’t inherit SCP controls.

The SCP policy

The following policy prevents anyone in the organization from changing the Amazon Bedrock data retention mode to anything other than none.

Important: New accounts default to inherit (not none). Before attaching this SCP, you must explicitly set each account to none. Start by running the following in each account:

aws bedrock put-account-data-retention --region us-east-1 --mode none

If you have hundreds, or thousands of AWS accounts, you will need a way to scale this. See the AWS re:Post article Automate Bedrock Zero Data Retention Across All Accounts in Your Organization to learn how.

Amazon Bedrock policy:

This policy is used to restrict data retention to only be set to none. Any other value than none will be denied.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RESTRICTBEDROCKDATARETENTION",
            "Effect": "Deny",
            "Action": [
                "bedrock:PutAccountDataRetention"
            ],
            "Resource": "*",
            "Condition": {
                "StringNotEquals": {
                    "bedrock:DataRetentionMode": "none"
                }
            }
        }
    ]
}

How it works

The Condition block uses StringNotEquals, meaning the deny fires for any value that isn’t none. This ensures:

Action Result
Setting mode to none Allowed
Setting mode to provider_data_share Denied by SCP
Setting mode to default Denied by SCP
Setting mode to inherit Denied by SCP

With all the preceding in place you might be wondering what this means for your organization:

  • No one can enable data sharing with model providers – Even account administrators receive Access Denied
  • Models requiring provider_data_share become permanently unavailable – Models that require data sharing (such as Claude Fable 5 and Claude Mythos 5, among others) will not work across the organization
  • All other models continue to work normally – Models that support none mode are unaffected
  • The setting cannot be bypassed – no IAM policy can override an SCP deny

Optional: Block project-level overrides

The bedrock-mantle endpoint supports project-level data retention settings. Without additional SCP coverage, someone could create or update a project with provider_data_share, bypassing the account-level restriction. To prevent this, extend your SCP to include the bedrock-mantle project actions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RESTRICTBEDROCKDATARETENTION",
            "Effect": "Deny",
            "Action": [
                "bedrock:PutAccountDataRetention",
                "bedrock-mantle:PutAccountDataRetention",
                "bedrock-mantle:CreateProject",
                "bedrock-mantle:UpdateProject"
            ],
            "Resource": "*",
            "Condition": {
                "StringNotEquals": {
                    "bedrock:DataRetentionMode": "none"
                }
            }
        }
    ]
}

Why doesn’t bedrock-runtime need project-level blocking? Projects don’t exist on the bedrock-runtime endpoint. The only way to change retention for bedrock-runtime traffic is the account-level bedrock:PutAccountDataRetention action, which the base SCP already blocks. The extra CreateProject and UpdateProject actions are only needed because bedrock-mantle allows per-project retention overrides; the project level control iisn’t required on bedrock-runtime.

Data retention and cross-Region inference

When using cross-Region inference profiles, it’s important to understand how data retention mode is evaluated: the mode is evaluated in the source AWS Region of your request, the Region where you make the API call. You don’t need to set the retention mode in every destination Region.

However, there’s an important caveat: while the mode check happens in your source Region, the data itself might be retained in the destination Region where the inference is processed. This is relevant for organizations tracking where retained data resides geographically.

What this means in practice

The following describes how this work in practice with data retention and inference.

  • If your source Region (for example, us-east-1) is set to provider_data_share, requests using a cross-Region inference profile will be permitted, regardless of the retention setting in the destination Region
  • If your source Region is set to none, requests to models requiring provider_data_share will be blocked at the source, before the request is ever routed to a destination Region
  • SCPs continue to apply globally, a single SCP at the root OU blocks provider_data_share in every Region automatically

SCPs are global

While data retention settings are helpful for granular control of data retention settings itself, SCPs can be used to apply data retention settings globally across all Regions automatically. A single SCP attached to the root OU blocks provider_data_share in every Region without needing to configure anything per-region. This is one of the key advantages of using an SCP for enforcement rather than relying on manual configuration.

Verify your configuration

You can verify your data retention settings and SCP enforcement using the AWS Software Development Kit, AWS Command Line Interface (AWS CLI), or the Amazon Bedrock console.

Check your current retention mode

The following provides are options that you can use for checking your current retention mode.

Using the Amazon Bedrock console:

In the AWS Management Console, go to Amazon Bedrock and choose Settings, and then choose Data retention. Here, you can see the current account-level retention mode and change it directly.

Using the AWS CLI (requires CLI version 2.35+):

aws bedrock get-account-data-retention --region us-east-1

Expected response:

{
  "mode": "none",
  "updatedAt": "2026-07-01T01:58:34.684Z"
}

Using the bedrock-mantle API (using a Bedrock API key):

curl https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
	-H "x-api-key: $BEDROCK_API_KEY"

Expected response:

{
  "mode": "none",
  "updated_at": 1719792000
}

Check a model’s effective mode and allowed modes

You can also use the bedrock-mantle API to check what retention mode is in effect for a specific model, and which modes that model supports:

curl https://bedrock-mantle.us-east-1.api.aws/v1/models/anthropic.claude-fable-5 \ 
  -H "x-api-key: $BEDROCK_API_KEY

Response:

{
  "id": "anthropic.claude-fable-5",
  "status": "available",
  "data_retention": {
    "mode": "provider_data_share",
    "source": "account",
    "allowed_modes": ["provider_data_share"]
  }
}

If the model shows "status": "unavailable", the status_reason field will explain the retention mode conflict.

Verify the SCP is working

To confirm your SCP is actively blocking data retention changes, attempt to set the mode to provider_data_share:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode provider_data_share

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "provider_data_share" }'

If the SCP is working, you’ll receive an Access Denied error:

An error occurred (AccessDeniedException) when calling the PutAccountDataRetention operation:
User: arn:aws:iam::123456789012:user/admin is not authorized to perform:
bedrock:PutAccountDataRetention with an explicit deny in a service control policy

If the SCP is not working, the request will succeed. If this happens, immediately revert:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode none

Then troubleshoot your SCP attachment:

  • Verify the SCP is attached to the root OU, not a child OU
  • Check the SCP policy syntax and condition keys
  • Remember: the AWS Organizations management account is exempt from SCPs—use an IAM policy to enforce policies on that account

Enable data retention for models that require it

For accounts where you want to use models requiring provider_data_share (accounts where the SCP isn’t applied), set the mode using AWS CLI, the API, or the console:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode provider_data_share

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "provider_data_share" }'

You can also do this in the Bedrock console in Data retention , under Settings.

Reset data retention back to none

To revert to zero data retention:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode none

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "none" }'

Manage project-level data retention

You can set data retention at the project level to allow different workloads within the same account to have different retention policies. Update a project’s data retention mode using the bedrock-mantle API:

# Set a project to provider_data_share
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "data_retention": { "mode": "provider_data_share" } }'

# Set a project to none (zero retention)
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "data_retention": { "mode": "none" } }'

# Check a project's current setting
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY"

How project-level retention resolves: The effective mode for any request is determined by taking the first non-inherit value in the project, account, model default hierarchy. If your project is set to none, it enforces zero retention regardless of the account setting. If your project is set to inherit, it defers to the account-level setting.

Note: Project-level data retention is managed exclusively through the bedrock-mantle API. There is no AWS CLI command for project-level settings. The preceding AWS CLI commands only manage the account-level setting through the Amazon Bedrock control plane.

Conclusion

In this post, I showed you the various methods for managing data retention within Amazon Bedrock, including project-level data retention and organization wide control you can implement using SCPs. Choose the combination that matches your requirements and consult the Amazon Bedrock documentation to confirm each model’s mode requirements before deployment.

For more information about Amazon Bedrock data retention, see the data retention documentation. For SCPs, see service control policies in the AWS Organizations User Guide.

Additional resources

Try the examples in this post and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.


Rob Higareda

Rob Higareda

Rob is a Principal Solutions Architect in the AWS Security Risk and Compliance organization at AWS, focused on risk assessment for AI-powered services. Rob joined AWS with 20+ years of experience as a systems engineer. He works primarily with regulated customers at AWS and is focused on security and infrastructure design.

Restrict AWS Management Console access to expected networks with sign-in resource-based policies and RCPs

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/restrict-aws-management-console-access-to-expected-networks-with-sign-in-resource-based-policies-and-rcps/

Amazon Web Services (AWS) recently announced support for resource-based policies and resource control policies (RCPs) for AWS Sign-In. By using resource-based policies and RCPs, you can restrict access to the AWS Management Console sign-in and aws login CLI sessions to requests from your expected networks, your on-premises data center networks, and your Amazon Virtual Private Cloud (Amazon VPC) VPCs.

Sign-in resource-based policies and RCPs support several security objectives: restricting console sign-in to corporate networks, limiting which principals can sign-in to the console, and applying consistent network perimeter controls across an entire AWS Organizations organization.

In this post, we walk through a common use case: a financial services company restricting console access to its corporate network for regulatory compliance. We show you how to implement this using a sign-in resource-based policy for a single account, verify the controls with AWS CloudTrail, and explain how these policies integrate with AWS Management Console Private Access and the broader AWS data perimeter framework.

Restricting console sign-in access to a corporate network

Consider a financial services company that requires access to AWS Management Console sign-in to originate from the corporate network. The company has the following requirements:

  • Users sign in to the console only from the corporate VPN, office network, or customer VPC.
  • Sign-in attempts from personal networks, public Wi-Fi, or other unexpected locations must be denied.
  • A designated principal should retain access from any network to prevent lockout.
  • All sign-in attempts (allowed and denied) must be logged to CloudTrail for compliance evidence.

In the steps that follow, we show you how to create a resource-based policy to enforce these requirements on a single account.

Prerequisites

  • AWS Command Line Interface (AWS CLI) installed and configured with the latest version.
  • Permission to manage Sign-in resource policies. Attach the AWS managed policy AWSSignInResourcePolicyManagement or grant permissions to the following actions to respective principals:
    • Manage resource permission statements: signin:PutResourcePermissionStatement, signin:DeleteResourcePermissionStatement, signin:ListResourcePermissionStatements, signin:GetResourcePolicy.
    • Manage console authorization: signin:PutConsoleAuthorizationConfiguration, signin:GetConsoleAuthorizationConfiguration, signin:DeleteConsoleAuthorizationConfiguration
  • Identified corporate network: IP CIDR range or VPC ID.
  • Designated principal Amazon Resource Name (ARN) to exclude, so it retains access if network conditions change.

Note: For the complete list of AWS Sign-In actions see Actions, resources, and condition keys for AWS Sign-In in the Service Authorization Reference.

Step 1: Create resource permission statements

Most resource-based policies require the author to input the full policy document (JSON statements). A Sign-in resource permission statement is different: you provide parameters, and AWS Sign-In generates the policy for you.

The following command provides your corporate IP range, your VPC, and an excluded principal as parameters. AWS Sign-In uses these parameters to generate a policy that restricts console sign-in to those networks, while letting the excluded principal sign in from any network. You control the parameter values, not the policy structure. You can review the generated policy at any time with the get-resource-policy command.

Note: Creating resource permission statements has no effect until console authorization is enabled in Step 2, so you can review the complete policy before it takes effect. Write operations must target us-east-1.

To create resource permission statements

1. Open your terminal and ensure you have the latest AWS CLI installed.
2. Run the following command, replacing the placeholder values <my-vpc>, <my-vpc-region>, <my-corporate-cidr>, and <excluded-IAM-principal-arn> with your specific configuration:

aws signin put-resource-permission-statement \
  --source-vpc <my-vpc> \
  --requested-region <my-vpc-region> \
  --source-ip <my-corporate-cidr> \
  --excluded-principal <excluded-IAM-principal-arn> \
  --region us-east-1

3. Verify the command succeeded by checking for a statementId in the output.

Example output:
{
“statementId":"b2HfHli9qCF1P4eGNll13CrZtusXlcPxxVBqz2aYLjlAcWtWQHP6Hg0"
}

4. Review the complete resource-based policy by running get-resource-policy command.

aws signin get-resource-policy

Example output:

{
  "signinResourceBasedPolicy": {
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      }
    ]
  }
}

The generated policy contains four statements, grouped into two pairs. The first pair restricts access by network source—it denies any principal making a request from outside your corporate IP range (<my-corporate-cidr>) or your VPC (<my-vpc>). The second pair restricts which AWS Region your VPC can target—it denies requests originating from <my-vpc> unless they are directed at <my-vpc-region>. This Region binding is necessary because VPC IDs are only unique within a single Region.

AWS Sign-In evaluates these policies in two phases: before authentication and after authentication. The post-authentication evaluation repeats each time the console session requests new credentials. Within each pair, one statement covers the pre-authentication phase and one covers the post-authentication phase.

The pre-authentication statement evaluates the signin:Authenticate action. Since the principal is not yet authenticated in this phase, the statement uses the signin:PrincipalArn condition key to exempt your excluded principal. This key supports all principal types: root user, AWS Identity and Access Management (IAM) user, federated user, and role.

The post-authentication statement evaluates the signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token actions. AWS Sign-In evaluates these actions after authentication, when it issues the tokens that establish the console session. These actions do not support the signin:PrincipalArn key. Instead, they use aws:PrincipalArn, which resolves to the authenticated principal.

The aws:ResourceAccount value is the recipient account ID. AWS Sign-In pulls it automatically from your caller credentials, so you do not set it yourself. For the full list of supported actions and condition keys, including which keys apply at each phase and to each principal type, see Controlling console access with resource-based policies and resource control policies and AWS Sign-In condition keys reference.

Step 2: Turn on sign-in policy enforcement for your account

This step turns on enforcement of the policy you created in Step 1. Until you run this step, the resource permission statements you created in Step 1 have no effect.

5. Turn on enforcement of sign-in policies using the following command:

aws signin put-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

6. Verify the command succeeded by checking for a “consoleAuthorizationEnabled": true in the output.

Example output:

{
“Output": {
“consoleAuthorizationEnabled": true,
“scope": “ACCOUNT”,
“targetId": "<account-id>"
}
}

7. You can also verify the configuration by executing the get-console-authorization-configuration command as shown below:

aws signin get-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

8. To disable enforcement or remove individual statements, use delete-console-authorization-configuration or delete-resource-permission-statement. For more details, see Controlling console access with resource-based policies and resource control policies in the AWS Sign-In User Guide.

Verifying the implementation

Now that enforcement is active, sign-in attempts are evaluated against your resource-based policy. Verify the behavior by testing sign-in from different network conditions.

Scenario 1: Allowed sign-in from the corporate network

A principal signing in from the allowed corporate IP range or VPC succeeds normally. The CloudTrail event shows ConsoleLogin:Success

Example CloudTrail event details for successful console sign-in:

{
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROAEXAMPLEID:Dev1",
        "arn": "arn:aws:sts::123456789123:assumed-role/Developer/Dev1",
        "accountId": "123456789123"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "192.0.2.100",
    "responseElements": {
        "ConsoleLogin": "Success"
    },
    "eventID": "dd004e78-6447-4f56-8d2d-a795da66f598",
    "readOnly": false,
    "eventType": "AwsConsoleSignIn",
    "managementEvent": true,
    "recipientAccountId": "123456789123",
    "eventCategory": "Management"
}

Scenario 2: Denied sign-in from an unexpected network

A principal signing in from a network other than the allowed IP address range or a VPC endpoint attached to the source VPC, is blocked. The CloudTrail event shows ConsoleLogin: Failure with an error message identifying the policy that caused the denial:

Example CloudTrail event details for failed console sign-in:

{    
"userIdentity": {
    "type": "IAMUser",
    "accountId": "123456789123",
    "accessKeyId": "",
    "userName": "Dev1"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "198.51.100.76",
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/148.0.0.0 Safari/537.36",
    "errorCode": "AccessDenied",
    "errorMessage": "Authorization denied because of a resource-based policy",
    "requestParameters": null,
    "responseElements": {
        "ConsoleLogin": "Failure"
    },
"eventID": "d88a7543-ae89-4186-b1b6-d3116413f2ee",
"readOnly": false,
"eventType": "AwsConsoleSignIn",
"managementEvent": true,
"recipientAccountId": "123456789123",
"eventCategory": "Management"
}

The error message field shows the policy type that caused the denial: “Authorization denied because of a resource-based policy”.

Scaling with RCPs

The steps above apply a Sign-in resource-based policy to a single account. For organizations managing many accounts, RCPs offer a better path: they can be attached at the organization, OU, or account level in AWS Organizations and apply automatically to every account in scope. To view an RCP example, see here .

When a sign-in to the console is denied because of an RCP, the error message field shows the denial as “Authorization denied because of a resource control policy”.

Extending with Console Private Access and data perimeters

The sign-in resource-based policy you created controls which networks can reach your account’s sign-in flow. AWS Management Console Private Access adds a complementary control: from within your network, it limits console access to a known set of AWS accounts, preventing sign-in to unexpected AWS accounts.

Together, these capabilities contribute to a data perimeter for console access:

  • Network perimeter: Sign-in resource-based policies and RCPs restrict console sign-in to expected networks (corporate IP ranges, VPCs).
  • Identity perimeter: Sign-in resource-based policy and RCP ensure only trusted identities can sign in to the console. Console VPC endpoint policy and Sign-in VPC endpoint policy ensure only trusted identities can use the console from your VPC.
  • Resource perimeter: Sign-in VPC endpoint policy and Console VPC endpoint policy restrict which AWS accounts are reachable from your network.

The controls in this post focus on console access. To extend these perimeters to other AWS services and broader implementation scenarios, see the Data perimeter policy examples repository and the Data Perimeters Blog Post Series.

Conclusion

By using sign-in resource-based policies and RCPs, you can restrict AWS Management Console access to expected networks. These controls are available at no additional cost in all AWS commercial Regions.

To get started, see the AWS Sign-in User Guide. For organization-wide enforcement, see Resource control policies in the AWS Organizations User Guide.

If you have feedback about this post, submit comments in the Comments section below.

Swara Gandhi

Swara Gandhi is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Rishi Tripathy

Rishi Tripathy

Rishi is a Principal Product Manager on the AWS Identity and Access Management (IAM) team. He focuses on access control mechanisms that help enterprises secure their AWS environments at scale. He is passionate about building security primitives that are straightforward to adopt and hard to misconfigure.

CIRT insights: How to help prevent unauthorized account removals from AWS Organizations

Post Syndicated from Shannon Brazil original https://aws.amazon.com/blogs/security/cirt-insights-how-to-help-prevent-unauthorized-account-removals-from-aws-organizations/

The AWS Customer Incident Response Team works with customers to help them recover from active security incidents. As part of this work, the team often uncovers new or trending tactics used by various threat actors that take advantage of specific customer configurations and designs.

Understanding these tactics can help inform your architecture decisions, improve your response plans, and detect these situations if they occur in your environment.

This post examines a new approach we’re seeing threat actors use after they gain control of a customer account, which is to remove it from the customer’s AWS Organizations implementation and the policies and protections that structure provides.

The described tactic doesn’t take advantage of vulnerabilities within AWS services, instead it uses an unexpected opportunity created by a specific configuration or design to make unauthorized use of resources within an AWS account.

What’s happening?

This approach starts with the threat actor using credentials that have the organizations:LeaveOrganizationpermission grant. This permission provides access to the LeaveOrganizations API call, which, when called from a member account, attempts to remove that account from the organization.

It’s important to remember that while this approach might use a compromised root credential, threat actors can also use other methods to elevate their access until they have the required permission or the ability to assume a role that has this permission, or they have the ability to grant their current credential this permission. This is why a least privilege approach to authorization is critical to protect your environment. To learn more, see AWS Identity and Access Management (IAM) documentation and the AWS Organizations guidance on organizational unit (OU) design and service control policy (SCP) implementation.

The impact on your environment

After the account is removed from the organization, the restrictions inherited as a part of that organization—such as SCPs that were preventing destructive actions, limiting which AWS Regions could be used, or blocking specific API calls—no longer apply. The account is also no longer part of consolidated billing, so the organization’s billing alerts and cost anomaly detection will no longer cover activity in that account. AWS CloudTrail organization trails stop capturing events from the departed account, and Amazon GuardDuty findings managed through a delegated administrator will stop flowing to the central security account.

The result is frequently that the organization loses visibility into the account while it still contains resources for the organization. Related threat technique catalog entries:

Detecting this technique

When an account attempts to leave an organization, at least two API calls are logged in CloudTrail: organizations:AcceptHandshake and organizations:LeaveOrganization. If you have centralized logging configured, these might be among the last events you see from the compromised account. After it leaves the organization, it might default to logging events within the account to its own CloudTrail logs. The following CloudTrail events are associated with accounts joining or leaving an organization. These should be investigated unless they’re part of an approved operational workflow that’s used by your teams to manage AWS Organizations.

CloudTrail event What it indicates
A member account is leaving the organization
The account is accepting an invitation to join a different organization
An organization is inviting the account
The management account is removing a member account (different from a member leaving on its own)

Recommended steps to prevent this technique

Implement an SCP that denies the organizations:LeaveOrganization action. AWS Organizations provides detailed guidance on implementing this control, including the specific SCP policy JSON and advice on how to design your OU structure to accommodate legitimate account migrations while keeping the protection in place for production and development accounts.

SCPs act as guardrails that limit what any IAM policy can permit within member accounts. We strongly encourage every customer using AWS Organizations to verify whether this SCP is in place today and take steps to implement it if it is not. This SCP is quick to deploy and has minimal operational impact, providing a process to carefully manage and consider separating a member account from an organization.

Because this action can originate from any compromised IAM principal with the organizations:LeaveOrganization—not just root—the principle of least privilege for IAM permissions is an important complementary control. Limiting which users and roles can add, remove, or change policies, assume other roles, or modify their own permissions reduces the paths available for unauthorized permission changes. Regularly reviewing IAM policies for overly broad permissions—particularly iam:AttachRolePolicy, iam:AttachUserPolicy, iam:PutRolePolicy, and sts:AssumeRole with wide trust policies—will help reduce the scope of what a compromised principal can do.

Root account security remains important, because root compromise is a common entry point for this pattern. Enabling multi-factor authentication (MFA) on every root user, deleting any root access keys, and adopting centralized root access management to remove root credentials from member accounts entirely, will help reduce the risk.

Looking ahead

This technique highlights a broader theme that we see across engagements: threat actors are increasingly aware of how AWS governance controls work, and they’re taking deliberate steps to separate accounts from the controls that an organization provides. Disabling AWS CloudTrail, deleting Amazon GuardDuty detectors, and removing accounts from organizations are all variations of the same strategy: removing your accounts from the guardrails and visibility that would otherwise constrain their activity and help the customer respond.

The controls to prevent this are available today and straightforward to implement. We encourage teams to start with the AWS Organizations service team’s guidance and implement the DenyLeaveOrganizationSCP—it’s the single highest-impact, lowest-effort control for this technique. Beyond that, reviewing SCP coverage across your OU structure, verifying that both root credentials and IAM permissions are properly secured across all member accounts, and ensuring that your detection and response processes account for this technique will contribute to a stronger posture. The Threat Technique Catalog for AWS includes detection guidance for the underlying techniques.

Additional related resources

If you have feedback about this post, submit comments in the Comments section below.
Shannon Brazil

Shannon is a security engineer on the AWS Customer Incident Response Team (CIRT), specializing in digital forensics and cloud security investigations. Known in the community as 4n6lady, she is passionate about security education and mentoring the next generation of defenders.

Derek Ramirez

Derek Ramirez

Derek is a Security Engineer on the AWS Customer Incident Response Team (CIRT), where he gets to combine two things he’s passionate about: cybersecurity and building AI tools that help tackle challenging incident response questions. You can find him running through downtown Austin, working on his short-game in golf, or cheering loudly for the Dallas Cowboys.

Richard Billington

Richard Billington

Richard is a Sr. Security Engineer in the Asia-Pacific region of the AWS Customer Incident Response Team (a team that supports AWS Customers during active security events).

Choosing between single or multiple organizations in AWS Organizations

Post Syndicated from John White original https://aws.amazon.com/blogs/architecture/choosing-between-single-or-multiple-organizations-in-aws-organizations/

Organizations face critical architectural decisions that can impact their operations for years to come. Recently, I had the opportunity to collaborate with a cloud migration advisor on a question that challenges many enterprises during their cloud adoption journey: Is it better to maintain a single organization or implement multiple organizations? This same question was also asked on re:Post.

This question isn’t merely academic—it strikes at the heart of how businesses balance governance, security, cost efficiency, and operational flexibility in their cloud environments. With many partners and customers growing through acquisitions, reorganizations, or organic expansion, understanding the implications of AWS Organizations becomes increasingly important.

The discussion yielded a comprehensive analysis of key criteria that decision-makers should consider when evaluating their cloud organization strategy. Although maintaining separate organizations might offer stronger isolation and customized governance in the short term, the long-term benefits of consolidation—including volume discounts, simplified resource sharing, and reduced operational overhead—often make a compelling case for eventual migration to a single organization.

In this post, I explain the key advantages and disadvantages of both approaches and the scenarios where each model fits best.

AWS Organizations: The foundation for multi-account strategy

AWS Organizations provides a centralized way to manage multiple AWS accounts. With AWS Organizations, you can:

  • Consolidate billing across accounts.
  • Apply policies centrally using service control policies (SCPs).
  • Share resources between accounts such as virtual private clouds (VPCs) and directory services.
  • Enforce consistent governance through organizational units (OUs).

How it works

Most AWS customers adopt a single organization and create multiple accounts within it. However, some enterprises—particularly those with highly independent business units or strong regulatory requirements or those experiencing mergers and acquisitions—explore the option of creating multiple organizations.

With AWS Organizations, you can manage your accounts through the following steps:

  • Add accounts. Create new accounts or invite existing accounts to your organization.
  • Group accounts. Group accounts into organizational units (OUs) by use-case or workstream.
  • Apply policies. Apply policies to accounts or OUs, such as service control policies (SCPs) which create permission boundaries.
  • Enable AWS services. Enable AWS services integrated with AWS Organizations.

When to use a single organization

For most customers, a single organization provides the right balance of control, cost efficiency, and governance. This approach works well when:

  • You want centralized visibility and governance across AWS accounts.
  • Teams and business units operate under a shared corporate security policy.
  • You want to consolidate billing and optimize for volume discounts.
  • You want to share resources (such as networking or directory services) between accounts.
  • You want centralized compliance enforcement using SCPs, AWS Config, and AWS Security Hub.

A use case in which a single organization is preferred is a large global retailer with regional teams and application owners. Each team creates their own AWS accounts under a central IT governance framework. A core team is responsible for centrally managing regulatory and security standards across the entire company.

When to consider multiple organizations

There are cases where creating multiple organizations might make sense. These typically arise when:

  • You have independent business units with separate leadership, governance, and security requirements (for example, subsidiaries or franchises).
  • You’re in a regulated industry where strict segmentation between entities is legally required (for example, banking or healthcare).
  • You’re managing mergers and acquisitions, where newly acquired companies maintain their existing AWS footprint.
  • You want maximum isolation of the potential impact of issues, so that misconfigurations, security incidents, or policy changes in one organization don’t affect others.

An example of a situation where multiple organizations is preferred is a multinational financial services company with distinct retail banking, investment banking, and insurance divisions. Each division has its own regulatory body and distinct security requirements, so they each manage their own organization.

Another example might be a global software company that uses a separate organization as a sandbox to develop and test guardrails and SCPs prior to applying them to their primary organization.

Operational efficiency compared to risk isolation

When deciding between using single or multiple organizations, enterprises must balance operational efficiency with risk isolation. A single organization provides simplified management, volume discounts, and easier resource sharing and governance. Structuring the enterprise with multiple organizations means stronger security and failure isolation, greater governance flexibility, and better support for organizational autonomy.

The following table summarizes the core differences between these two approaches.

Criteria Single organization Multiple organizations
Billing Consolidated billing with volume discounts across accounts Each organization has independent billing; no cross- organization discounts
Governance Centralized SCPs and policies for accounts Each organization defines its own governance policies
Security isolation Shared security perimeter; SCPs apply globally Strong isolation between organizations
Access management Central AWS Identity and Access Management (IAM) roles and cross-account access setup No built-in cross- organization access; fully independent IAM
Scalability Supports thousands of accounts within a single organization Each organization is independent; you scale organizations separately
Resource sharing Easy sharing of VPCs, Amazon Machine Images (AMIs), and other resources within organization No built-in sharing between organizations
Operational overhead Lower; centralized governance reduces duplication Higher; governance, security, and operations duplicated per organization
Compliance and audit Centralized logging, AWS CloudTrail, and AWS Config across accounts Requires separate audit trails per organization
Risk isolation Misconfigurations could impact accounts Misconfigurations are contained within individual organizations
Flexibility Standardized controls across accounts Each organization can tailor controls to its specific needs

Conclusion

Most enterprises, especially those adopting AWS as part of a centralized IT strategy, find that a single organization is the best fit. However, for conglomerates, regulated businesses, and companies growing through acquisition, multiple organizations might be appropriate.

When helping customers design their AWS multi-account strategy, I recommend starting with a single organization and only considering multiple organizations when the isolation requirements outweigh the operational benefits of centralization.

For more information, refer to the following resources:


About the Authors

AWS Outposts monitoring and reporting: A comprehensive Amazon EventBridge solution

Post Syndicated from Matt Price original https://aws.amazon.com/blogs/compute/aws-outposts-monitoring-and-reporting-a-comprehensive-amazon-eventbridge-solution/

Organizations using AWS Outposts racks commonly manage capacity from a single AWS account and share resources through AWS Resource Access Manager (AWS RAM) with other AWS accounts (consumer accounts) within AWS Organizations. In this post, we demonstrate one approach to create a multi-account serverless solution to surface costs in shared AWS Outposts environments using Amazon EventBridge, AWS Lambda, and Amazon DynamoDB. This solution reports on instance runtime and allocated storage for Amazon Elastic Compute Cloud (Amazon EC2), Amazon Relational Database Services (Amazon RDS), and Amazon Elastic Block Store (Amazon EBS) services running on Outposts racks. In turn, teams can track the cost of infrastructure associated with their workloads across AWS accounts. This solution is a framework that can be customized to meet your organization’s specific business objectives.

Solution overview

The following is the Terraform-based reference architecture used to represent the solution, including EventBridge, DynamoDB, and Lambda across a multi-account environment. Relevant launch events are tracked in EventBridge that invoke Lambda functions, which are logged in DynamoDB tables (see sample code). This allows reporting on captured event data through the AWS SDK for Python (Boto3). AWS architecture diagram showing data collection and workload account integration with EventBridge, CloudTrail, and Outposts
Figure 1: Reference architecture for reporting solution on AWS Outposts 

Prerequisites

The following prerequisites are necessary to implement this solution:

Walkthrough

The following sections walk you through how to deploy this solution.

Deploying in data collection account

Step 1: Create a bucket in-Region to hold the Terraform state file in the data collection account.

aws s3 mb s3://state-bucket-name

Step 2: Clone the repository.On your local machine, clone the repository that contains the sample by running the following command:

git clone https://github.com/aws-samples/sample-outposts-monitoring-and-reports.git

Navigate to the cloned repository by running the following command:cd sample-outposts-monitoring-and-reports/data_collection

Step 3: Edit the providers.tf to configure the AWS provider.


provider "aws" {
  region = ""
}

Step 4: Edit the backend.tf to provide the Terraform state bucket and Outposts anchored AWS Region.

terraform {
  backend "s3" {
    bucket = ""
    key    = "terraform.tfstate"
    region = ""
  }
}

Step 5: Modify the variables.tf.From the root directory of the cloned repository, modify the variables.tf file with the target Region and workload accounts as shown in the following example. The target Region is the collection destination.

variable "aws_region" {
  description = "AWS region for resources"
  type        = string
  default     = ""
}

variable "allowed_account_id" {
  description = "AWS account ID allowed to put events to the event bus"
  

}

Initialize the configuration directory of the data collection account to download and install the providers defined in the configuration by running the following command:

terraform init

All resources are deployed with minimal permissions to serve as an example. We recommend viewing all configurations to make sure that they meet your organizational security policies. Step 6: Deploy infrastructure in the data collection account.Run terraform plan on the configuration to and review which resources are created:

terraform plan

When you have reviewed the plan, run the following command and enter “yes” to accept the changes and deploy:

terraform apply

Deployment should take less than 5 minutes. If you receive any errors, review the previously mentioned steps to ensure that you followed them in their entirety. If the errors persist, reach out to AWS Support for additional guidance.

Deploying in workload account

The data collection account receives events from EventBridge and performs intelligent analysis and storage from the AWS Outposts resource data.Step 1: Navigate to the workload account directory by running the following command:

cd ../workload_account

Step 2: Edit variables.tf to set up the Region and event bus Amazon Resource Name (ARN). 

variable "aws_region" {
  description = "AWS region for resources"
  type        = string
  default     = ""
}

variable "event_bus_arn" {
  description = "target event bus arn"
  type        = string
  default     = ""
}

Edit the code to update the event bus name.

Step 3: Run the following command to create the backend.tf and create the Terraform state bucket for each workload account.

./init-backend.sh

This is an idempotent operation that creates a file from the template and a bucket with a fixed name including the account ID if it doesn’t exist. 

Step 4: Initialize the configuration directory of the Data Collection Account to download and install the providers defined in the configuration by running the following command:

terraform init

Step 5: Deploy the infrastructure in the Data Collection Account.Run a terraform plan on the configuration and review which resources are created:

terraform plan

After you have reviewed the plan, run the following command and enter “yes” to accept the changes and deploy:

terraform apply

Deployment should take less than 5 minutes. If you receive any errors, follow the troubleshooting steps in the previous section.

At this point, any Amazon EC2 or Amazon RDS instances and Amazon EBS volumes are logged to the DynamoDB tables in the data collection account. Repeat Steps 3–5 for each workload account running resources on AWS Outposts with appropriate account credentials. If you’re deploying at scale and using AWS Control Tower consider using AWS Control Tower Account Factory for Terraform (AFT).

Running monthly reports

With this solution in place, reports can be generated on demand. These reports can be customized by modifying the Python example scripts shown to support your needs. Reports can be created from a local machine with credentials that have access to the DynamoDB tables in the data collection account. The examples were created from the source directory of the data collection account git repository. Run the following command to view the report for Amazon RDS usage in September 2025:

./rds_runtime_calculator.py --year 2025 --month 9 --output rds_report.csv

Spreadsheet showing RDS database instances with configuration details, storage allocation, and operational status in us-west-2 region

Figure 2: Example of RDS runtime report 


Run the following command to view the report for Amazon EBS usage in September 2025:

./ebs_volume_reporter.py --year 2025 --month 9 --output ebs_report.csv


EBS volume tracking table showing volume configurations, lifecycle hours, and active/deleted status in us-west-2

Figure 3: Example of EBS usage report 


Run the following command to view the report for Amazon EC2 usage in September 2025:

./ec2_runtime_calculator.py --month 9 --year 2025 --output ec2_report.csv

EC2 instance tracking table showing c5.large instances with runtime hours and running/stopped status on AWS Outposts

Figure 4: Example of EC2 runtime report 


Cleaning up

Complete the following steps to clean up the resources that were deployed by this solution. For each workload account, complete the following:

cd sample-outposts-monitoring-and-reports/workload_account
terraform destroy 

Enter “yes” to proceed. You can then manually empty and remove the terraform state S3 bucket for that account.

For the data collection, complete the following:

cd ../data_collection
terraform destroy

Enter “yes” to proceed. You can then manually empty and remove the terraform state S3 bucket for that account.

Conclusion

Customers who have shared multi-account Outposts deployments can use this solution to create account level reporting for Outposts resources using real-time event capture and processing, state analysis and categorization, historical usage metrics, and serverless architecture. Teams can use this to visualize and report on the costs of running their workloads on Outposts. The event-driven design supports accurate tracking while maintaining low operational overhead. The solution scales effectively across multiple Outposts and accounts, providing a unified view of hybrid infrastructure. Keep in mind that you can extend the functionality described here to meet your business objectives.

Deploy this solution today using the GitHub repository to gain financial insights to share with the tenants of your Outposts workload accounts. Reach out to your AWS account team, or fill out this form to learn more about Outposts.

Amazon Bedrock Guardrails supports cross-account safeguards with centralized control and management

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-bedrock-guardrails-supports-cross-account-safeguards-with-centralized-control-and-management/

Today, we’re announcing the general availability of cross-account safeguards in Amazon Bedrock Guardrails, a new capability that enables centralized enforcement and management of safety controls across multiple AWS accounts within an organization.

With this new capability, you can specify a guardrail in a new Amazon Bedrock policy within the management account of your organization that automatically enforces configured safeguards across all member entities for every model invocation with Amazon Bedrock. This organization-wide implementation supports uniform protection across all accounts and generative AI applications with centralized control and management. This capability also offers flexibility to apply account-level and application-specific controls depending on use case requirements in addition to organizational safeguards.

  • Organization-level enforcements apply a single guardrail from your organization’s management account to all entities within the organization through policy settings. This guardrail automatically enforces filters across all member entities, including organizational units (OUs) and individual accounts, for all Amazon Bedrock model invocations.
  • Account-level enforcement enables automatic enforcement of configured safeguards across all Amazon Bedrock model invocations in your AWS account. The configured safeguards in the account-level guardrail apply to all inference API calls.

You can now establish and centrally manage dependable, comprehensive protection through a single, unified approach. This supports consistent adherence to corporate responsible AI requirements while significantly reducing the administrative burden of monitoring individual accounts and applications. Your security team no longer needs to oversee and verify configurations or compliance for each account independently.

Getting started with centralized enforcement in Amazon Bedrock Guardrails
You can get started with account-level and organization-level enforcement configuration in the Amazon Bedrock Guardrails console. Before the enforcement configuration, you need to create a guardrail with a particular version to support the guardrail configuration remains immutable and cannot be modified by member accounts and complete prerequisites for using the new capability such as resource-based policies for guardrails.

To enable account-level enforcement, choose Create in the section of Account-level enforcement configurations.

You can choose the guardrail and version to automatically apply to all Bedrock inference calls from this account in this Region. With general availability, we introduce the new feature defining which models will be affected by the enforcement with either Include or Exclude behavior.

You can also configure selective content guarding controls for system prompts and user prompts with either Comprehensive or Selective.

  • Use Comprehensive when you want to enforce guardrails on everything, regardless of what the caller tags. This is the safer default when you don’t want to rely on callers to correctly identify sensitive content.
  • Use Selective when you trust callers to tag the right content and want to reduce unnecessary guardrail processing. This is useful when callers handle a mix of pre-validated and user-generated content, and only need guardrails applied to specific portions.

After creating the enforcement, you can test and verify enforcement using a role in your account. The account-enforced guardrail should automatically apply to both prompts and outputs.

Check the response for guardrail assessment information. The guardrail response will include enforced guardrail information. You can also test by making a Bedrock inference call using InvokeModel, InvokeModelWithResponseStream, Converse, or ConverseStream APIs.

To enable organization-level enforcement, go to AWS Organizations console and choose Policies menu. You can enable the Bedrock policies in the console.

You can create a Bedrock policy that specifies your guardrail and attach it to your target accounts or OUs. Choose Bedrock policies enabled and Create policy. Specify your guardrail ARN and version and configure the input tags setting for in the AWS Organizations. To learn more, visit Amazon Bedrock policies in AWS Organizations and Amazon Bedrock policy syntax and examples.

After creating the policy, you can attach the policy to your desired organizational units, accounts, root in the Targets tab.

Search and select your organization root, OUs, or individual accounts to attach your policy, and choose Attach policy.

You can test that the guardrail is being enforced on member accounts and verify which guardrail is enforced. From a member account attached, you should see the organization enforced guardrail under the section Organization-level enforcement configurations.

The underlying safeguards within the specified guardrail are then automatically enforced for every model inference request across all member entities, ensuring consistent safety controls. To accommodate varying requirements of individual teams or applications, you can attach different policies with associated guardrails to different member entities through your organization.

Things to know
Here are key considerations to know about GA features:

  • You can now choose to include or exclude specific models in Bedrock for inference, enabling centralized enforcement on model invocation calls. You can also choose to safeguard partial or complete system prompts and input prompts. To learn more, visit Apply cross-account safeguards with Amazon Bedrock Guardrails enforcement.
  • Ensure you are specifying the accurate guardrail Amazon Resource Names (ARN) in the policy. Specifying an incorrect or invalid ARN will result in policy violations, non-enforcement of safeguards, and the inability to use the models in Amazon Bedrock for inference. To learn more, visit Best practices for using Amazon Bedrock policies.
  • Automated Reasoning checks are not supported with this capability.

Now available
Cross-account safeguards in Amazon Bedrock Guardrails is generally available today in the all AWS commercial and GovCloud Regions where Bedrock Guardrails is available. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. Charges apply to each enforced guardrail according to its configured safeguards. For detailed pricing information on individual safeguards, visit Amazon Bedrock Pricing page.

Give this capability a try in the Amazon Bedrock console and send feedback to AWS re:Post for Amazon Bedrock Guardrails or through your usual AWS Support contacts.

— Channy

Sovereign failover – Design for digital sovereignty using the AWS European Sovereign Cloud

Post Syndicated from Ivo Kammerath original https://aws.amazon.com/blogs/architecture/sovereign-failover-design-for-digital-sovereignty-using-the-aws-european-sovereign-cloud/

Organizations operating across multiple jurisdictions need to consider the impact of regulatory changes or geopolitical events on their access to cloud infrastructure. This post explains how to design failover architectures that span AWS partitions—including the AWS European Sovereign Cloud, AWS GovCloud (US) and other AWS Regions in the global infrastructure — so workloads can continue operating when sovereignty requirements shift.

Although the AWS European Sovereign Cloud is designed to help customers with operational autonomy and data residency requirements, it can also be used to address broader geopolitical and sovereignty risks. This post explores the architectural patterns, challenges, and best practices for building cross-partition failover, covering network connectivity, authentication, and governance. By understanding these constraints, you can design resilient cloud-native applications that balance regulatory compliance with operational continuity.

Understanding sovereignty risks

Digital sovereignty entails managing digital dependencies — deciding how data, technologies, and infrastructure are used, and reducing the risk of loss of access, control, or connectivity. As with any disaster recovery strategy, there are several means to provide continuity for the systems to be designed. Most of them involve some form of failover architecture, i.e. providing a second set of infrastructure to be used when the disaster incapacitates the original infrastructure. What differs for sovereign disaster recovery are the control mechanics and structures of the target to fail over to. Incorporating the AWS European Sovereign Cloud into your workload design adds failover capabilities that help you to reestablish or maintain enhanced sovereignty if the primary environment becomes unavailable.

As regulatory requirements evolve, modern failover architectures must account for sovereign environments such as the AWS European Sovereign Cloud, AWS GovCloud (US), and multi-vendor deployments. This post focuses on three core areas for incorporating sovereignty requirements into failover design: failover strategy, network connectivity across isolated partitions, and authentication and authorization in cross-partition architectures. These patterns apply to both short regional outages and long-term partition failures.

Understanding AWS partitions

As a global cloud provider, AWS operates multiple infrastructure partitions tailored to meet specific operational and regulatory requirements. In addition to its AWS global infrastructure, AWS offers specialized partitions such as AWS GovCloud for US government agencies, the AWS China Regions, and the AWS European Sovereign Cloud for customers that require stringent data residency and control within the EU.

Each partition is a logically isolated group of AWS Regions with its own set of resources, including AWS Identity and Access Management (IAM). Because of this separation, partitions act as hard boundaries. Credentials don’t carry over, and services such as Amazon S3 and features like S3 Cross-Region Replication or AWS Transit Gateway inter-region peering cannot function across partitions. These limitations are intentional, providing operational isolation. AWS GovCloud (US), launched in 2011, supports US public sector customers with compliance needs such as FedRAMP and ITAR. The AWS China regions are operated through local partnerships to meet Chinese data sovereignty laws. Similarly, the AWS European Sovereign Cloud is a partition built entirely within the EU, launched in 2026.

These partitions provide enhanced data control and physical infrastructure isolation, making them essential if you operate in regulated sensitive sectors and need to satisfy strict compliance requirements.

Key benefits of AWS partitions

AWS introduced partitions for several reasons. They are key to helping customers meet country-specific compliance and regulatory requirements, whether in AWS GovCloud (US), AWS China, or the AWS European Sovereign Cloud. This is underpinned by multiple safeguards and controls, including physical, logical, and operational separation of the cloud infrastructure between partitions. This directly corresponds to the security aspects of partitions. Partitions allow AWS to provide a complete isolation of resources, which helps manage security, especially for architectures running sensitive workloads.

Another important point to keep in mind when talking about partitions is service availability. Not all AWS services are available in every partition. To learn more about the AWS services available by Region, refer to AWS Capabilities by Region.

Cross-partition architectures

A cross-partition architecture enables partition failover by deploying resources and infrastructure across multiple isolated AWS partitions. Because partitions are fully separated by identity, networking, and service boundaries, failover can’t simply switch between them as within a single partition or region. Instead, environments must be pre-provisioned and kept in sync through internal or external tooling. Without such an architecture, failover between partitions is impractical. Cross-partition architectures make failover possible but require duplicate infrastructure, separate identity systems, and custom data synchronization.

Figure 1: Different reasons for failover and their possible locations

When designing cross-Region or cross-partition failover strategies, the choice of Regions depends on the type of disaster you want to mitigate:

  • Natural disasters – select Regions in different geographic zones or with distinct geographic features.
  • Technical disasters – separate workloads across independent parts of the global technical infrastructure, such as power grids, networks, and other shared resources.
  • Human-driven disasters – consider political, socioeconomic, and legal factors that might affect operations.

Figure 2: Active-active failover scenario including a sovereign failover option

Partition failover

Cross-partition workloads arise from industry needs to maintain continuity across sovereign domains while meeting regional regulations. Examples include military and defense connecting specialized clouds (such as AWS GovCloud (US)) with commercial environments, and emergency response systems requiring secure partition isolation combined with unified management (a single pane of glass approach). Control planes managing workloads across partitions are critical for handling multi-tenant structures, enabling centralized metrics, log aggregation, onboarding, security management and more.

However, cross-partition connections increase operational complexity, security and compliance overhead, costs, and governance challenges. These factors make it important to implement such architectures only when they are truly required. Standard cloud resilience models range from simple backups to multi-site setups, and can be implemented across multiple Availability Zones as well as multiple Regions. The same concept equally applies across multiple partitions. We can move backups into a second partition to be able to recover into that partition. Equally we can run an application pilot light in another partition. This greatly reduces the cost of the infrastructure required in the second partition because it will only be built up when needed. Finally, warm standby or multi-site active-active setups mainly differ in the need for more complex network synchronization across partitions.

Figure 3: Different types of disaster recovery scenarios

You might also consider vendor independence as an additional sovereignty requirement when planning failover. One way to achieve vendor independence is to use another cloud provider. However, failing over to another AWS partition is simpler than switching cloud providers because you can reuse your infrastructure as code templates across partitions.

Reasons to connect partitions

Although partitions are designed for isolation, some workloads within a partition might need to communicate with workloads in less regulated partitions or with external systems accessible over the public internet. For such instances several architectural strategies and the corresponding architectural decisions should be considered. There might be use cases where you need AWS Services to communicate across partitions and orchestrate actions spanning multiple partitions, such as:

  • Cross-domain applications
  • Feature parity and service availability
  • Cost-optimization while meeting security demands
  • Infrastructure consolidations
  • Control plane patterns

Implementing these use cases requires a deeper look into the technical aspects of connecting partitions from both a network standpoint and a security standpoint.

Regional connections vs. connected partitions

Regional connections let you link AWS Regions within the same partition using features like S3 Cross-Region Replication and Transit Gateway peering, facilitating relatively seamless workload distribution and failover within the partition’s global infrastructure. Understanding the distinction between regional connections and connected partitions is crucial for designing resilient, compliant architectures that meet both operational and regulatory demands.

Connecting partition networks

You can connect AWS partitions in three ways: internet connectivity secured by TLS, IPsec Site-to-Site VPN over the internet, or through an AWS Direct Connect gateway to on-premises routers or using Direct Connect point of presence (PoP) partner connections to another Direct Connect PoP. Each approach offers different trade-offs in terms of security complexity and recovery. For more information about connectivity patterns between AWS GovCloud (US) and the global AWS infrastructure, see Connectivity patterns between AWS GovCloud (US) and AWS commercial partition. In addition to the customer gateway solution shown previously, partners located in Direct Connect PoPs can provide cross-partition connectivity services. These services can move traffic from one Direct Connect PoP to another. Such a setup enables dedicated lines between the AWS European Sovereign Cloud Direct Connect PoPs and the Direct Connect locations in other partitions.

Because IAM credentials don’t work across partitions, you need to create separate roles or use external identity providers. Common approaches include using IAM roles with trust relationships and external IDs, AWS Security Token Service (AWS STS) regional endpoints, resource-based policies, or cross-account roles managed through AWS Organizations. A modern best practice is to federate identities from a single, centralized identity provider to multiple partitions, avoiding the need for IAM users wherever possible. If IAM users are still used, credentials can be stored in AWS Secrets Manager, rotated using Lambda, and a backup user can improve availability. These patterns are often combined with standard access controls, such as Amazon API Gateway with authorizers, to secure cross-partition interactions. For a deeper dive into cross-partition authentication and authorization with AWS IAM, see IAM Identity Center for AWS environments spanning AWS GovCloud (US) and standard Regions.

When securing communication between AWS partitions, certificate-based approaches present both opportunities and challenges. Because AWS Certificate Manager (ACM) certificates and AWS Private Certificate Authority (AWS Private CA) are bound to individual partitions, you must typically deploy and manage separate public key infrastructure (PKI) infrastructures in each environment, including dedicated root CAs and manual handling of private key transfers. To establish secure cross-partition communication, a more advanced solution involves using double-signed certificates, where root CAs in each partition cross-sign each other’s certificates, creating a bidirectional chain of trust. Implementing this requires setting up root CAs with AWS Certificate Manager Private CA, establishing cross-signing agreements, managing trust stores across partitions, and handling complex certificate validation and revocation checks. You must also comply with differing regulatory requirements and maintain detailed audit trails. Although this approach adds operational complexity, it is essential for enabling authenticated, encrypted communication across isolated partitions, particularly in regulated environments where security and compliance are paramount.

Managing AWS Organizations across partitions

Setting up AWS European Sovereign Cloud accounts within your AWS Organization must be done in a completely separate organization. In the AWS GovCloud (US) partition, accounts can be paired into a commercial organization, as described in Inviting Accounts into an Organization for AWS GovCloud. With sovereignty as the main goal, failing over to an AWS European Sovereign Cloud-only state is simpler if the AWS Organizations setup is separate from the start. This doesn’t require starting from scratch. Instead, you can manage the same organizational units (OUs) and policies for the AWS European Sovereign Cloud by reusing your existing deployment automation.

Ideally, AWS Organizations account structures should be separated to make it straightforward to use the AWS landscape within the AWS European Sovereign Cloud without relying on the other partitions.

Figure 4: connectivity and service distribution across AWS partitions like the AWS European Sovereign Cloud

Security controls should be tailored per partition using distinct Service Control Policies (SCPs), with AWS Control Tower managing the commercial side. Networking requires isolated Transit Gateways, separate Amazon Route 53 DNS zones, and secure cross-partition communication using AWS PrivateLink. For monitoring, AWS Config aggregators and AWS Security Hub instances must be configured separately in each partition, while consolidated billing can be managed through Organizations. It’s important to consider limitations (for example, AWS Control Tower can’t directly manage AWS GovCloud (US) or AWS European Sovereign Cloud accounts), and the limited availability of some AWS Organizations features in these partitions. Overall, this approach supports governance, security, and operational clarity across partitions.

Conclusion

Navigating sovereignty-driven cloud architectures requires a strategy that addresses partition isolation, network connectivity, and secure cross-partition authentication. Prioritizing sovereignty in failover design adds complexity, but it might be worth the trade-off if your workloads need protection against geopolitical risks or regulatory changes. Start by identifying the disaster scenarios that matter most to your business, then select the simplest architecture that addresses those risks. By designing proactively for evolving regulations, you can maintain both compliance and resilience in the cloud.


About the authors

AWS Control Tower introduces a Controls Dedicated experience

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-control-tower-introduces-a-controls-dedicated-experience/

Today, we’re announcing a Controls Dedicated experience in AWS Control Tower. With this feature, you can use Amazon Web Services (AWS) managed controls without the need to set up resources you don’t need, which means you get started faster if you already have an established multi-account environment and want to use AWS Control Tower only for its managed controls. The Controls Dedicated experience gives you seamless access to the comprehensive collection of managed controls in the Control Catalog to incrementally enhance your governance stance.

Until now, customers were required to adopt and configure many recommended best practices which meant implementing a full AWS landing zone at the time of setting up a multi-account environment. This setup included defining the prescribed organizational structure, required services, and more, in AWS Control Tower to start using landing zone. This approach is helpful to ensure a well-architected multi-account environment, however, for customers who already have an established, well-architected multi-account environment and only want to use AWS managed controls, it was more challenging for them to adopt AWS Control Tower. The new Controls Dedicated experience provides a faster and more flexible way of using AWS Control Tower.

How it works
Here’s how I define managed controls using the Controls Dedicated experience in AWS Control Tower in one of my accounts.

I start by choosing Enable AWS Control Tower on the AWS Control Tower landing page.

I have the option to set up a full environment, or only set up controls using the Controls Dedicated experience. I opt to set up controls by choosing I have an existing environment and want to enable AWS Managed Controls. Next, I set up the rest of the information, such as choosing the Home Region from the dropdown list so that AWS Control Tower resources are provisioned in this Region during enablement. I also select Turn on automatic account enrollment for AWS Control Tower to enroll accounts automatically when I move them into a registered organization unit. The rest of the information is optional; I choose Enable AWS Control Tower to finalize the process, and the landing zone setup begins.

Behind the scenes, AWS Control Tower installed the required service-linked AWS Identity and Access Management (IAM) roles, and to use detective controls, service-linked Config Recorder in AWS Config in the account where I’m deploying the AWS managed controls. The setup is completed, and now I have all the infrastructure required to use the controls in this account. The dashboard gives a summary of the environment such as the organizational units that were created, the shared accounts, the selected IAM configuration, the preventive controls to enforce policies, and detective controls to detect configuration violations.


I choose View enabled controls for a list of all controls that were installed during this process.

Good to know
Usually, an existing AWS Organizations account is required before you can use AWS Control Tower. If you’re using the console to create controls and don’t already have an Organizations account, one will be set up on your behalf.

Earlier, I mentioned a service-linked Config Recorder. With a service-linked Config Recorder, AWS Control Tower prevents the resource types needed for deployed managed controls from being altered. You have flexibility and the ability to keep your own Config Recorders, and only the configuration items for the resource types that are required by your managed detective controls will be enabled, which optimizes your AWS Config costs.

Now available
Controls Dedicated experience in AWS Control Tower is available today in all AWS Regions where AWS Control Tower is available.

To learn more, visit our AWS Control Tower page. For more information related to pricing, refer to AWS Control Tower pricing. Send feedback to AWS re:Post for AWS Control Tower or through your usual AWS Support contacts.

– Veliswa.

Moeve: Controlling resource deployment at scale with AWS CloudFormation Guard Hooks

Post Syndicated from Pablo Sánchez Carmona original https://aws.amazon.com/blogs/devops/moeve-controlling-resource-deployment-at-scale-with-aws-cloudformation-guard-hooks/

This post is co-written with Rayco Martínez Hernández, Head of Cloud Governance at Moeve.

Moeve, formerly known as Cepsa, is a global integrated energy company with over 90 years of experience and more than 11,000 employees. Moeve is committed to driving Europe’s energy transition and accelerating decarbonization efforts. The company has embraced digital transformation to enhance energy efficiency, safety, and sustainability, focusing on investments in green hydrogen, second-generation biofuels, and ultra-fast electric vehicle charging infrastructure.

At Moeve, we decided to make AWS Control Tower our central governance tool and the foundation of our landing zone at the end of 2022. However, as an organization that wants to ensure that all deployed resources comply with the established requirements, it was challenging for us to remediate errors or vulnerabilities that arise when resources were deployed without compliance with our security definitions. The foundation of controls should be proactive. This is where AWS CloudFormation Hooks, along with other AWS measures like Service Control Policies (SCPs), play a differential role.

We have become familiar with CloudFormation Hooks thanks to the Guard Rules that we deploy as part of our proactive deployment policy on AWS. There are times when you want to block the deployment of Amazon API Gateway without security, Amazon VPC security groups with source 0.0.0.0/0, or with an ALL port range open. In these and other cases, we want to take a step further and create our own controls that are more in line with our own policies, and now we can do so in a simple and agile way, using the managed hooks launched in November 2024.

To be able to use these tools, it is essential, among other things, to ensure that resource deployments are only done through Infrastructure as Code (IaC) tools.

Would you like to know how we achieved it? Let’s get to it!

Background

At Moeve, we ensure that all our deployments within our organization are done through IaC. We enforce this by requiring all deployments to go through CloudFormation, which also allows us to enforce organizational policies using CloudFormation Guard Hooks.

However, for teams with more advanced technical expertise, we allow the use of the AWS Cloud Development Kit (CDK). The AWS CDK enables developers to define infrastructure using general-purpose programming languages, which facilitates code reuse, modular design, and better integration with existing development workflows. It provides high-level abstractions that accelerate the definition of common AWS patterns, while also allowing low-level control when needed. Even though it introduces an abstraction layer, the CDK synthesizes into standard CloudFormation templates, maintaining full compatibility with our governance and compliance mechanisms based on CloudFormation Guard Hooks.

We have several ways to perform deployments: directly launching actions against CloudFormation from the AWS Command Line Interface (CLI), through pipelines, or even by executing actions from code. However, the common basis for these deployments is that they cannot be done with Permission Sets associated with individuals. Users do not have access to deploy resources directly; they have read access and can assume a role that can deploy resources.

To make this more user-friendly, we have a small tool that assumes the role with enough permissions and deploys the template code we specify, with just a call like this:

cloudformation-deployer test.yml

It is crucial to make these controls easy for developers if you want them to comply with the established security measures.

Solution

At Moeve, as a best practice, we have delegated the management of Cloudformation StackSets to an AWS account different from the management account. In this account, we deploy an Amazon S3 bucket where we will store all the files for the CloudFormation Guard hooks or the AWS Lambda functions if they are Lambda type. In Figure 1, you can see a simplified version of our multi-account architecture when deploying resources using StackSets.

Multi-Account structure when building CloudFormation resources using CloudFormation StackSets. There are two central accounts (Management & Delegated Admin) and two child Accounts.

Figure 1. AWS CloudFormation StackSets configuration in a multi-Account environment

An example of a stack that manages the buckets can be seen below:

AWSTemplateFormatVersion: "2010-09-09"

Description: |
  This template creates an Amazon S3 bucket that you can use to deploy an AWS CloudFormation hook.

Parameters:
  GuardHooksBucketName:
    Type: String
    Description: Name for S3 bucket storing the CloudFormation Guard hooks
  OrgId:
    Description: Organization Id which is in the format o-xyzabcdefg
    Type: String
    AllowedPattern: ^o-[a-z0-9]{10,32}$
  
Resources:
  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Sub ${GuardHooksBucketName}-${AWS::Region}-${AWS::AccountId}
      BucketEncryption:
        ServerSideEncryptionConfiguration:
          - ServerSideEncryptionByDefault:
              SSEAlgorithm: AES256
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        BlockPublicPolicy: true
        IgnorePublicAcls: true
        RestrictPublicBuckets: true
      LifecycleConfiguration:
        Rules:
          - Id: MultipartClean
            Status: Enabled
            AbortIncompleteMultipartUpload:
              DaysAfterInitiation: 5
      Tags:
        - Key: project
          Value: shared
      VersioningConfiguration:
        Status: Enabled

  S3BucketPolicy:
    Type: AWS::S3::BucketPolicy
    Properties:
      Bucket: !Ref S3Bucket
      PolicyDocument:
        Version: 2012-10-17
        Statement:
          - Sid: AllowSSLRequestsOnly
            Effect: Deny
            Action: s3:*
            Resource:
              - !Sub ${S3Bucket.Arn}/* # "arn:aws:s3:::arn:aws:s3:::<bucket-name>/<path>/*"
              - !Sub ${S3Bucket.Arn} # "arn:aws:s3:::arn:aws:s3:::<bucket-name>/<path>/"
            Principal: '*'
            Condition:
              Bool:
                aws:SecureTransport: 'false'
          - Sid: AllowOrgAccountsDeployAccess
            Effect: Allow
            Principal:
              AWS: "*"
            Action: "s3:GetObject"
            Resource: !Join
              - ""
              - - "arn:aws:s3:::"
                - !Ref S3Bucket
                - /*
            Condition:
              ForAnyValue:StringLike:
                "aws:PrincipalOrgPaths": !Sub "${OrgId}/*"

With this, we achieve having a centralized S3 bucket with an access policy according to which anyone within our organization can access and retrieve the objects. Versioning is configured to keep previous versions of the hooks we deploy. Then, in the bucket, we will store the files of our hooks, differentiating them by folders.

Child Accounts

For the child accounts, we will deploy a StackSet in the central account over the Organizational Units (OUs) that are defined. Auto-deployment will be configured so that all new Accounts added to the OU acquire these same hooks.

Check the example below where an S3 bucket will be deployed to store the logs of the hooks with the IAM role that the hooks will use, and two hooks: to evaluate the creation and update of API Gateway.

AWSTemplateFormatVersion: "2010-09-09"

Description: |
  Registers the hook in the AWS CloudFormation Private Registry and bucket to logs.

Parameters:
  CustomHooksLogBucketName:
    Type: String
    Description: Name for S3 bucket storing the CloudFormation Guard hook logs
  GuardHooksBucketName:
    Type: String
    Description: Name for S3 bucket storing the CloudFormation Guard hooks

Resources:
  # S3 bucket used to store logs generated by CloudFormation Guard hooks
  LogBucket:
    Type: AWS::S3::Bucket
    Properties:
     # Bucket name is built dynamically with account ID and region
      BucketName: !Sub ${CustomHooksLogBucketName}-${AWS::AccountId}-${AWS::Region}
      BucketEncryption:
        ServerSideEncryptionConfiguration:
          - ServerSideEncryptionByDefault:
              SSEAlgorithm: AES256	# Enforce AES256 encryption
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        BlockPublicPolicy: true
        IgnorePublicAcls: true
        RestrictPublicBuckets: true
      LifecycleConfiguration:		# Manage bucket lifecycle
        Rules:
          - Id: MultipartClean
            Status: Enabled
            AbortIncompleteMultipartUpload:
              DaysAfterInitiation: 5	# Abort incomplete uploads after 5 days
          - Id: ExpireAfterOneWeek
            Status: Enabled
            Prefix: ""
            ExpirationInDays: 7	# Expire objects after 7 days
      Tags:
        - Key: project
          Value: shared
  # Bucket policy that enforces SSL-only access to the log bucket
  S3BucketPolicy:
    Type: AWS::S3::BucketPolicy
    Properties:
      Bucket: !Ref LogBucket
      PolicyDocument:
        Version: 2012-10-17
        Statement:
          - Sid: AllowSSLRequestsOnly
            Effect: Deny
            Action: s3:*
            Resource:
              - !Sub ${LogBucket.Arn}/* # "arn:aws:s3:::arn:aws:s3:::<bucket-name>/<path>/*" # Apply to all objects in the bucket
              - !Sub ${LogBucket.Arn} # "arn:aws:s3:::arn:aws:s3:::<bucket-name>/<path>/" # Apply to the bucket itself
            Principal: '*'
            Condition:
              Bool:
                aws:SecureTransport: 'false' 	# Deny if not using HTTPS
   # IAM Role that CloudFormation Guard hooks assume to interact with S3
  GuardHookRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:		# Trust policy for CloudFormation hooks
        Statement:
          - Action: sts:AssumeRole
            Condition:
              StringEquals:
                aws:SourceAccount: !Ref 'AWS::AccountId'
              StringLike:
                'aws:SourceArn': !Sub arn:${AWS::Partition}:cloudformation:${AWS::Region}:${AWS::AccountId}:type/hook/Moeve-*/*
            Effect: Allow
            Principal:
              Service:
                - hooks.cloudformation.amazonaws.com
                - resources.cloudformation.amazonaws.com
        Version: "2012-10-17"
      MaxSessionDuration: 8400
      Path: /
      Policies:
        - PolicyName: HookS3Policy		# Policy granting permissions to write/read from the log bucket
          PolicyDocument:
            Statement:
              - Action:
                - 's3:GetEncryptionConfiguration'
                - 's3:ListAllMyBuckets'
                - 's3:ListBucket'
                - 's3:GetObject'
                - 's3:PutObject'
                Effect: Allow
                Resource:
                  - !Sub arn:${AWS::Partition}:s3:::${LogBucket}
                  - !Sub arn:${AWS::Partition}:s3:::${LogBucket}/*
            Version: "2012-10-17"
        - PolicyName: HookGeneralS3Policy	# Policy granting read access to the bucket containing Guard rules
          PolicyDocument:
            Statement:
              - Action:
                - 's3:GetEncryptionConfiguration'
                - 's3:ListBucket'
                - 's3:GetObject'
                Effect: Allow
                Resource:
                  - !Sub arn:${AWS::Partition}:s3:::${GuardHooksBucketName}
                  - !Sub arn:${AWS::Partition}:s3:::${GuardHooksBucketName}/*
            Version: "2012-10-17"
      Tags:
        - Key: project
          Value: shared

   # Guard hook that validates API Gateway methods before provisioning
  GuardHookApiGateway: 
    Type: AWS::CloudFormation::GuardHook
    Properties:
      ExecutionRole: !GetAtt GuardHookRole.Arn
      LogBucket: !Ref LogBucket
      Alias: Moeve::ApiGatewayAuthorization::Coe
      FailureMode: FAIL	# Fail the operation if validation fails
      HookStatus: ENABLED
      TargetOperations:
        - RESOURCE	# Applies at the resource level
      TargetFilters:
        Actions:
          - CREATE		# Triggered on CREATE operations
        TargetNames:
          - AWS::ApiGateway::Method
        InvocationPoints:
          - PRE_PROVISION		# Runs before resource provisioning
      RuleLocation:
        Uri: !Sub
          - s3://${GuardS3Bucket}/${GuardS3File}	# Location of Guard rules in S3
          - GuardS3Bucket: !Ref GuardHooksBucketName
            GuardS3File: APIGATEWAY/ApiGatewaySecureMethod.guard
      StackFilters:
        FilteringCriteria: ALL
        StackNames:
          Exclude:
            - !Ref AWS::StackName	# Exclude the current stack from evaluation

   # Guard hook that validates API Gateway at stack UPDATE level
  GuardHookApiGatewaySR:
    Type: AWS::CloudFormation::GuardHook
    Properties:
      ExecutionRole: !GetAtt GuardHookRole.Arn
      LogBucket: !Ref LogBucket
      Alias: Moeve::ApiGatewayAuthorizationwithSR::Coe
      FailureMode: FAIL
      HookStatus: ENABLED
      TargetOperations:
        - STACK		# Applies at the stack level
      TargetFilters:
        Actions:
          - UPDATE		# Triggered on UPDATE operations
      RuleLocation:
        Uri: !Sub
          - s3://${GuardS3Bucket}/${GuardS3File}
          - GuardS3Bucket: !Ref GuardHooksBucketName
            GuardS3File: APIGATEWAY/ApiGatewaySecureMethodwithSR.guard
      StackFilters:
        FilteringCriteria: ALL
        StackNames:
          Exclude:
            - !Ref AWS::StackName

It is very important to configure backdoors to avoid blocking our own deployments when working with hooks deployed with CloudFormation StackSets across our organization or in OUs with multiple accounts. For this, we will configure a filter in the hook so that it does not activate on the stack that manages them. If this filter is not applied, it may happen that due to a misconfiguration, the stack cannot be updated and has to be deleted entirely.

Examples

In the following examples, we are going to ensure that no one can deploy an unsecured API Gateway, but at the same time, we do not want to break the current deployments. For this, we have defined two hooks.

When the custom hooks are triggered during deployment, they analyze the CloudFormation template and targets resources of type AWS::ApiGateway::Method, excluding methods that use the OPTIONS HTTP verb. The hooks apply two sequential validation rules to ensure that all API operations are properly secured.

The first rule checks whether each method defines either the ApiKeyRequired or the AuthorizationType property. If neither is present, the hook fails with a clear message: “Fallo en el paso 1 porque no existe ApiKeyRequired o AuthorizationType” (“Step 1 failed because there is no ApiKeyRequired or AuthorizationType”). If the first condition is satisfied, the second rule verifies whether the values themselves enforce security. Specifically, it checks that ApiKeyRequired is set to true, or that AuthorizationType is defined and not set to NONE. If not, the deployment is blocked again with the message: “Fallo en el paso 2, porque existe AuthorizationType o ApiKeyRequired, pero no son valores válidos.” (“Step 2 failed, because AuthorizationType or ApiKeyRequired exists, but they are not valid values.”).

If any of these rules fail, CloudFormation immediately stops the deployment before any resources are created. This avoids partial or insecure configurations and ensures consistency with organizational security standards. The error appears directly in the CloudFormation console or in CI/CD logs and includes the custom message defined in the hook, helping developers quickly identify the issue.

The development team receives immediate feedback during deployment, whether through their CI/CD pipeline (like CodePipeline or GitHub Actions) or the AWS console. The hook’s clear, custom messages make it easy to pinpoint and fix issues. In more mature environments, these failures can also trigger alerts, update dashboards, or create automated tickets, ensuring security enforcement without slowing down delivery.

The responsibility to fix the issue usually lies with the same team that wrote the template, since the error occurs before any infrastructure is provisioned. This approach allows teams to move quickly while still respecting the compliance and security controls in place. In cases where the issue is tied to a broader policy update, the resolution might involve collaboration with the platform or security team

Hook 1: Activates when an API Gateway is created. This hook checks at the resource level for Resources.Type == 'AWS::ApiGateway::Method', and if it does not meet the requirements, this resource cannot be deployed.

let api_gateway_method = Resources.*[ Type == 'AWS::ApiGateway::Method'
  Properties.HttpMethod != /(?i)options/  
]

#
# Primary Rules
#

rule api_gw_authorization_method_check when %api_gateway_method !empty {
    %api_gateway_method{
        Properties.ApiKeyRequired exists or
        Properties.AuthorizationType exists
        <<Fallo en el paso 1 Porque no existe ApiKeyRequired o AuthorizationType>>
    }
}

rule api_gw_authorization_method_check_2 when api_gw_authorization_method_check {
    %api_gateway_method{
        Properties.ApiKeyRequired == true or
        Properties.AuthorizationType != /(?i)none/
        <<Fallo en el paso 2, porque existe AuthorizationType o ApiKeyRequired, pero no son valores validos. >>
    }
}

Hook 2: Activates when an API Gateway is updated. This hook checks at the resource level for Resources.Type == 'AWS::ApiGateway::Method', and if it does not meet the requirements, this resource cannot be deployed.

let api_gateway_method = Resources.*[ Type == 'AWS::ApiGateway::Method'
    Properties.HttpMethod != /(?i)options/  
    Metadata.guard.SuppressedRules not exists or
    Metadata.guard.SuppressedRules.* != "API_GW_METHOD_AUTHORIZATION_TYPE_RULE"
]

#
# Primary Rules
#

rule api_gw_authorization_method_check when %api_gateway_method !empty {
    %api_gateway_method{
        Properties.ApiKeyRequired exists or
        Properties.AuthorizationType exists
        <<Fallo en el paso 1 Porque no existe ApiKeyRequired o AuthorizationType>>
    }
}


rule api_gw_authorization_method_check_2 when api_gw_authorization_method_check {
    %api_gateway_method{
        Properties.ApiKeyRequired == true or
        Properties.AuthorizationType != /(?i)none/
        <<Fallo en el paso 2, porque existe AuthorizationType o ApiKeyRequired, pero no son valores validos. >>
    }
}

To avoid breaking existing deployments, a backdoor is configured so that if specific metadata is applied, the hook will not activate, and deployments can continue without modifying the code beyond the metadata.

AWSTemplateFormatVersion: '2010-09-09'

Description: |
  This template creates an Amazon API Gateway REST API. It shows an example on how to suppress specific checks from CloudFormation Guard.

Resources:
  Api:
    Type: AWS::ApiGateway::RestApi
    Properties:
      Name: myAPI
  MyApiGatewayMethod:
    Type: AWS::ApiGateway::Method
    Metadata:
      guard:
        SuppressedRules:
          - API_GW_METHOD_AUTHORIZATION_TYPE_RULE
    Properties:
      RestApiId: !Ref Api
      ResourceId: !GetAtt Api.RootResourceId
      HttpMethod: GET
      AuthorizationType: 'NONE'
      ApiKeyRequired: false
      Integration:
        IntegrationHttpMethod: 'POST'
        Type: 'MOCK'

  OptionsMethod:
    Type: 'AWS::ApiGateway::Method'
    Properties:
      AuthorizationType: 'NONE'
      HttpMethod: 'OPTIONS'
      RestApiId: !Ref Api
      ResourceId: !GetAtt Api.RootResourceId
      Integration:
        IntegrationHttpMethod: 'POST'
        Type: 'MOCK'

Conclusion

The implementation of our own hook controls in CloudFormation has significantly improved infrastructure management and deployment within Moeve. This capability has allowed us to achieve a balance between flexibility, autonomy, and governance at scale. One of the key benefits is the automation of validations and specific controls, which helps us reduce manual errors and ensure greater consistency in deployments. This also enhances traceability and simplifies infrastructure maintenance, ensuring that our configurations adhere to established best practices.

From a security perspective, having custom rules allows us to strengthen regulatory compliance and minimize risks. We can ensure that only secure configurations aligned with our operational needs are implemented, reducing vulnerabilities and improving our cloud security posture. Preventing incorrect configurations from the start of the resource lifecycle also contributes to greater system stability and resilience. By avoiding infrastructure failures, we create more reliable environments that are prepared for growth.

Additionally, by ensuring optimal configurations during resource deployment, we optimize resource usage and avoid bottlenecks, resulting in better performance. This, in turn, helps us manage costs more effectively by preventing the use of unnecessary or oversized resources. Also, automating controls reduces manual intervention and minimizes waste, making our operations more efficient and sustainable over time.

In summary, the creation and management of our own hooks in CloudFormation provide us with full control over our infrastructure, ensuring an optimal balance between security, scalability, and operational efficiency. This strengthens our ability to innovate without compromising governance, enabling us to operate more agilely and securely in the cloud.

About the author(s)

Rayco Martínez Hernández

Rayco is Head of Cloud Governance at Moeve, building secure, compliant, and efficient cloud environments. He holds a degree in Computer Science and currently pursuing a Master’s degree in Cybersecurity. Passionate about cloud strategy and governance, Rayco focuses on adopting AWS with confidence and control. When not working on cloud initiatives, he enjoys exploring new technologies and spending time outdoors in the Canary Islands.

Pablo Sánchez Carmona

Pablo is a Senior Network Specialist Solutions Architect at AWS, where he helps customers to design secure, resilient and cost-effective networks. When not talking about Networking, Pablo can be found playing basketball or video-games. He holds a MSc in Electrical Engineering from the Royal Institute of Technology (KTH), and a Master’s degree in Telecommunications Engineering from the Polytechnic University of Catalonia (UPC).

Ignacio Rodríguez García

Ignacio is a Technical Account Manager at AWS. In his role, he provides advocacy and strategical technical guidance in order to help customers plan and build solutions using AWS best practices. He holds a MSc in Engineering from Télécom Paris, and a Master’s degree in Telecommunications Engineering from the Polytechnic University of Madrid (UPM). In his free time, Ignacio enjoys playing sports, spending time with his friends, and traveling.

Minimize risk through defense in depth: Building a comprehensive AWS control framework

Post Syndicated from Luis Pastor original https://aws.amazon.com/blogs/security/minimize-risk-through-defense-in-depth-building-a-comprehensive-aws-control-framework/

Security and governance teams across all environments face a common challenge: translating abstract security and governance requirements into a concrete, integrated control framework. AWS services provide capabilities that organizations can use to implement controls across multiple layers of their architecture—from infrastructure provisioning to runtime monitoring. Many organizations deploy multi-account environments with AWS Control Tower, or Landing Zone Accelerator to implement a foundational baseline of controls and security architecture. Once their environment is provisioned, organizations typically look to add additional detective controls from services such as AWS Security Hub and AWS Config based on security, compliance, and operational requirements. While this sequence is a great start, there are more opportunities during this time to implement layered defense-in-depth coverage to enhance your security posture.

Highly regulated industries such as fintech and financial services are often viewed as the gold standard for governance and security controls. While these sectors have established robust frameworks, there’s consistently room for improvement and valuable lessons for other industries looking to enhance their control environments. However, many organizations struggle to move beyond a basic compliance-focused approach. In our experience working with customers across various sectors, this limited perspective often stems from multiple factors, including:

  • Immediate compliance pressures
  • Resource constraints
  • Limited understanding of control maturity pathways
  • Focus on detection rather than prevention
  • A tendency to prioritize technology-agnostic controls over bult-in AWS capabilities, leading to unnecessarily complex implementations

The good news? A more comprehensive approach that uses AWS preventative, proactive, detective, and responsive controls can significantly reduce risk while decreasing operational overhead through automation.

In this post, we outline a practical framework that you can adopt to evolve your security and governance controls strategy. We explore how your organization can mature from a detection-focused security posture to a multi-layered control framework, using real-world examples across the resource lifecycle, including infrastructure-as-code testing and preventative controls such as service control policies (SCPs), resource control policies (RCPs), and declarative policies (DPs).

Drawing from best practices in highly regulated industries while incorporating modern cloud capabilities through services such as AWS Organizations and AWS Control Tower, we provide a structured framework that you can use to elevate your organization’s control environment beyond basic compliance requirements.

Customer challenges in implementing controls

Organizations face several significant challenges when attempting to implement a comprehensive control framework in AWS. Let’s explore the main obstacles:

Resource constraints and expertise gaps

Security teams often find themselves caught between limited resources and expanding responsibilities in the cloud. With constrained budgets and personnel, teams typically gravitate toward quick wins through detective controls, which appear straightforward to implement initially. While this provides immediate visibility, it can leave critical gaps in security posture. Many teams lack comprehensive expertise across all control types, particularly in implementing preventative, proactive, and responsive controls effectively. The pressure to demonstrate immediate security improvements, combined with day-to-day operational demands, frequently results in tactical solutions rather than strategic, layered security approaches.

Analysis paralysis

Deciding which tools to prioritize can be a challenge; the breadth of options and extensive capabilities available across AWS security services and third-party tools can feel overwhelming at times. Security teams struggle to determine the optimal mix of controls for their environment and where to begin implementation. This challenge is compounded by the complexity of mapping technical compliance requirements to cloud-focused capabilities and maintaining visibility into emerging threats as the security landscape evolves. The layers of abstraction created by proliferating security controls can further obscure clear decision-making, leading teams to delay critical security improvements while seeking perfect solutions.

Misunderstanding of defense in depth

Defense in depth as a concept is good, but it can be misunderstood and difficult to achieve, leading to vulnerabilities in the security architecture. A common misconception is that a single strong control, separation of duties in AWS Identity and Access Management (IAM) roles, least permission in IAM policies, and so on, provide sufficient protection. This overlooks the crucial value of implementing controls at multiple points and how different control types can be combined to create a robust security posture. Teams often miss how organizational controls like SCPs can work in harmony with workload-specific controls to achieve greater protection. The role of preventative controls in guiding technical implementations is frequently under appreciated.

Maturity journey challenges

The path to security maturity presents numerous obstacles. Many organizations remain stuck in the early stages, implementing detective controls but never progressing to preventative measures. Security controls are often implemented in isolation, without consideration for the broader security landscape. Organizations struggle to create and follow a clear roadmap for evolving their security posture, and measuring improvement over time proves challenging.

Scale and consistency issues

As AWS environments grow, maintaining consistent governance and security becomes increasingly complex. Organizations face mounting challenges in managing exceptions and special cases across their expanding infrastructure. These interrelated challenges often result in controls implementations that fail to achieve their intended risk reduction goals. You need a structured approach to overcome these obstacles and implement comprehensive security controls, which we explore in the following sections.

Strategic investment in security

While implementing comprehensive controls requires an initial investment in time and resources, the long-term benefits fundamentally transform how organizations operate.

The foundation for this transformation begins with establishing baseline controls through proven starting points such as AWS Control Tower and its customization options. AWS Control Tower provides building blocks for secure multi-account architectures with hundreds of security capabilities and proactive controls already built in. Rather than trying to create baselines from scratch by wrangling vast amounts of account-level or resource-specific controls, you can use these accelerators to rapidly establish a strong security foundation. With these baseline controls in place, this transformation extends beyond security teams to enable the entire organization to operate more efficiently. Development and operations teams can deploy faster with confidence when security guardrails are in place. Security becomes an enabler rather than a bottleneck, so that teams across the organization can innovate while maintaining a strong security posture.

As you mature your organization’s control framework through automation and layered defenses, a security transformation occurs. Security teams shift from constant firefighting to proactive risk management. Automated policy enforcement replaces manual reviews, and the time previously spent on routine tasks can be redirected to strategic initiatives.

Understanding control types and their interplay

AWS defines distinct types of controls to build a comprehensive security framework. Let’s examine each type and how they work together, using a common scenario: preventing public Amazon Simple Storage Service (Amazon S3) bucket exposure.

Preventative controls

Preventative controls establish the foundation of a secure environment by defining the policies, standards, and requirements that guide security implementations. At their core, these controls encompass corporate security policies that outline acceptable resource configurations across the organization. They work in conjunction with compliance requirements and frameworks to help maintain regulatory alignment, while architectural standards and guidelines provide technical direction for implementations. Data classification policies play a crucial role by determining specific security requirements based on data sensitivity.

To illustrate how preventative controls work in practice, consider a common S3 bucket security requirement. A typical preventative control might establish a corporate policy stating All S3 buckets must be private by default, with public access granted only through an approved exception process. This simple but effective policy sets clear expectations and requirements before a technical implementation begins.

  • Organization level: SCPs blocking public S3 bucket creation.
  • Resource level:
    • RCPs enforcing network access controls, such as requiring authenticated access or limiting requests to your organization’s network range.
    • SCPs to stop malicious overwrites of S3 objects using SSE-C encryption by blocking s3:PutObject requests with customer-provided keys unless explicitly allowed, paired with AWS IAM Roles Anywhere for short-term credential enforcement.
```json
// SCP to block SSE-C unless explicitly allowed 
{
  "Version": "2012-10-17",
  "Statement": [
 {
     "Sid": "DenySSECEncryption",
     "Effect": "Deny",
     "Action": "s3:PutObject",
     "Resource": "*",
     "Condition": {
         "Null": {
               "s3:x-amz-server-side-encryption-customer-algorithm": "false"}
            } }
  ]}

Proactive controls

Proactive controls act as an early warning system, identifying and addressing potential security issues before they manifest in your environment. These controls work by validating configurations and changes against established security requirements during the development and deployment phases. Through automated validation and policy enforcement at build and deploy time, proactive controls help prevent misconfigurations from reaching production environments, reducing the operational overhead of fixing security issues after the fact. Think of proactive controls as your first line of defense in maintaining a secure cloud environment. In AWS, these can be implemented at multiple levels:

  • Amazon S3 Block Public Access settings at the account level.
  • Policy-as-code checks in continuous integration and delivery (CI/CD) pipelines (such as CFN-Nag, or AWS Config proactive rules).
  • AWS CloudFormation hooks for pre-deployment validation and policy enforcement.
  • AWS Config rules in proactive mode to evaluate resources before creation.
  • At the resource level, you can use:
    • IAM policies restricting bucket policy modifications
    • CloudFormation Guard rules

#####################################
##           Gherkin               ##
#####################################
# Rule Identifier:
#    S3_BUCKET_SERVER_SIDE_ENCRYPTION_ENABLED
# Description:
#   Checks if your Amazon S3 bucket either has the Amazon S3 default encryption enabled or that the Amazon S3 bucket policy
#   explicitly denies put-object requests without server side encryption that uses AES-256 or AWS Key Management Service.
# Reports on:
#    AWS::S3::Bucket
# Evaluates:
#    AWS CloudFormation
# Rule Parameters:
#    NA
# Scenarios:
# a) SKIP: when there are no S3 resource present
# b) PASS: when all S3 resources Bucket Encryption ServerSideEncryptionByDefault is set to either "aws:kms" or "AES256"
# c) FAIL: when all S3 resources have Bucket Encryption ServerSideEncryptionByDefault is not set or does not have "aws:kms" or "AES256" configurations
# d) SKIP: when metadata includes the suppression for rule S3_BUCKET_SERVER_SIDE_ENCRYPTION_ENABLED
#
# Select all S3 resources from incoming template (payload)
#
let s3_buckets_server_side_encryption = Resources.*[ Type == 'AWS::S3::Bucket'
  Metadata.cfn_nag.rules_to_suppress not exists or 
  Metadata.cfn_nag.rules_to_suppress.*.id != "W41"
  Metadata.guard.SuppressedRules not exists or
  Metadata.guard.SuppressedRules.* != "S3_BUCKET_SERVER_SIDE_ENCRYPTION_ENABLED"
]
rule S3_BUCKET_SERVER_SIDE_ENCRYPTION_ENABLED when %s3_buckets_server_side_encryption !empty {
  %s3_buckets_server_side_encryption.Properties.BucketEncryption exists
  %s3_buckets_server_side_encryption.Properties.BucketEncryption.ServerSideEncryptionConfiguration[*].ServerSideEncryptionByDefault.SSEAlgorithm in ["aws:kms","AES256"]
  <<
    Violation: S3 Bucket must enable server-side encryption.
    Fix: Set the S3 Bucket property BucketEncryption.ServerSideEncryptionConfiguration.ServerSideEncryptionByDefault.SSEAlgorithm to either "aws:kms" or "AES256"
  >>
}

Source: aws-guard-rules-registry

Detective controls

Detective controls provide continuous visibility into your security posture by monitoring for and identifying potential security violations or unauthorized changes within your environment. While preventative controls aim to stop issues before they occur, detective controls help you maintain awareness of your security state and can identify when preventative controls have been bypassed or failed. These controls form a critical layer of defense by enabling rapid identification of security issues and providing the visibility needed for effective incident response and compliance reporting. While many organizations start and stop here, detective controls are only part of the solution:

  • AWS Config rules monitoring for public buckets
  • Security Hub findings to flag non-compliant resources
  • AWS IAM Access Analyzer evaluations

Responsive controls

Responsive controls complete the security lifecycle by providing automated and manual mechanisms to address security issues after they’re detected. These controls define and implement the actions taken when security violations are identified, ranging from automated remediation of common misconfigurations to coordinated incident response procedures for complex security events. By establishing clear response patterns and using automation where appropriate, responsive controls help facilitate consistent and timely handling of security issues while reducing the mean time to remediation. Responsive controls address violations when they occur:

The power comes not from implementing these controls in isolation, but from using them together in a coordinated way. This layered approach begins with preventative controls to establish the requirements, followed by proactive controls to block most potential violations at the source. Issues that manage to slip through are caught by detective controls, while responsive controls automatically remediate identified problems. Throughout this process, comprehensive documentation tracks issues, remediation plans, and progress, such as through a plan of action and milestones (POAM), helping to make sure that compliance requirements are met and improvements can be measured over time.

Implementation lifecycles: Ideal compared to reality

You can follow one of two paths when implementing security controls: starting fresh with a comprehensive approach or evolving from an existing detective-focused implementation. Let’s examine both scenarios.

Starting fresh: The ideal approach

When starting from scratch, you have a unique opportunity to build your security and governance following an ideal approach. Your team can take advantage of this clean slate to architect controls and processes methodically, free from legacy constraints. The following steps offer guidance though establishing a strong foundation while maintaining the flexibility you need as your business grows.

  • Rationalize controls against requirements and risk profile:
    • Choose appropriate security frameworks (for example, CIS and NIST).
    • Map compliance, regulatory, legal, and contractual requirements to your base framework.
    • Define clear security objectives and success criteria for your security and compliance program.
  • Design a comprehensive control strategy:
    • Document control requirements across all four types (preventive, proactive, detective, and responsive controls). You can use the framework to decide which controls are best for each type of requirement.
    • Plan implementation phases and priorities.
    • Define metrics for measuring effectiveness.
  • Implement controls in layers:
    • Start with AWS Control Tower, which gives you foundational controls to mature from. You can add customizations if required.
    • Think about additional preventative controls that can help establish a stronger security and compliance posture.
    • Deploy proactive controls to stop violations.
    • Add detective controls as safeguards.
    • Implement responsive controls for automated or manual remediation.
  • Monitor and assess effectiveness
    • Evaluate control performance against defined metrics.
    • Identify gaps and areas for improvement.
    • Adjust controls based on emerging threats and changing requirements.
    • Implement continuous improvement feedback loop.

Evolution from detective controls: The common path

Most organizations find themselves starting with detective controls and face challenges in maturing from there:

  • Initial state:
    • Baseline detective controls through Security Hub and AWS Config
    • Manual remediation processes
    • Limited visibility into security posture
  • Maturation steps:
    • Analyze findings to identify patterns
    • Implement automated remediation for common issues
    • Add preventative and proactive controls based on recurring events
    • Periodically refine and update policies
  • Optimization:
    • Review control effectiveness
    • Identify gaps in coverage
    • Implement additional preventative, proactive, detective, and responsive measures
    • Automate processes where possible

The goal: Comprehensive and layered security controls

The goal of implementing security controls across multiple layers isn’t just about compliance or following best practices—it’s about creating a robust, resilient security posture that can effectively help prevent, detect, and respond to security issues. Let’s explore why this approach is crucial:

Why multiple control layers matter

Security controls shouldn’t exist in isolation. When implementing a security requirement, you should consider:

  • How can we prevent this issue from occurring?
  • How will we detect if our preventative controls fail?
  • What should happen when we detect a violation?
  • What policies and standards guide these decisions?

Moving beyond detection

While detective controls are important, they signal that a security violation has already occurred. A mature security posture requires:

  • Strong preventative controls to stop violations before they happen
  • Detective controls as a safety net if there is drift or a violation
  • Automated remediation where possible, to reduce exposure time
  • Clear policies to guide implementation and decisions
  • Measuring success

You should measure the effectiveness of your control framework through several key performance indicators. Success can be seen in the steady reduction of security findings over time, coupled with decreasing time-to-remediation metrics. The maturity of the framework becomes evident through an increasing percentage of automated remediation activities and a declining number of recurring issues. These improvements manifest in better audit outcomes, providing tangible evidence that the control framework is delivering its intended results.

Practical implementation: From theory to practice

Let’s examine how to implement a comprehensive control framework using a common security requirement: preventing exposure of sensitive data through public S3 buckets. This example demonstrates how different control types work together to create defense in depth. While not every control might be necessary for every situation, each should be carefully considered and evaluated based on various factors including system criticality, data sensitivity, operational overhead, and organizational risk tolerance. The decision to implement or omit specific controls should be deliberate and documented, rather than occurring by default.

The architecture will have layers and components like the following.

  • Preventative layer:
    • Service control policies (SCPs) or resource control policies (RCPs)
    • S3 Block Public Access
    • IAM policies
  • Detective layer:
  • Responsive layer:
    • AWS Config auto-remediation
    • Lambda functions
    • Systems Manager automation

Building controls at each layer

An effective security and compliance strategy includes all four types of security controls. While preventative controls are a first line of defense to help prevent unauthorized access or unwanted changes to your network, it’s important to make sure that you establish detective and responsive controls so that you know when an event occurs and can take immediate and appropriate action to remediate it. Using proactive controls adds another layer of security because it complements preventative controls, which are generally stricter in nature.

Begin by defining your security objectives, then establish clear policies to meet those objectives:

  • Define organizational and business objectives:
    • Identify data protection goals
    • Determine acceptable risk levels
    • Align with compliance requirements
  • Establish clear policies:
    • For example, document business requirements for external data sharing and access controls in security policies. These requirements will drive technical decisions around AWS storage configurations such as S3 bucket policies and public access settings.
    • Define permitted use cases for public access.
    • Establish exception processes.
    • Set clear ownership and responsibilities.

Deploy preventative guardrails:

  • Organization level:
    • SCPs to block public bucket creation at the organization level
    • Account-level S3 Block Public Access settings to enforce account-level restrictions
  • Resource level:
    • IAM policies restricting bucket policy modifications
    • S3 bucket policy templates with controlled deployment
    • RCPs to enforce rules on specific resource types across your organization

Deploy proactive guardrails:

  • Infrastructure as code:
    • Implement policy-as-code checks in CI/CD pipelines using:
      • CloudFormation Guard
      • cfn-nag
      • AWS Config proactive rules
    • Integrate with pull request workflows
  • AWS Control Tower proactive controls:
    • Enable relevant optional AWS Control Tower guardrails

Add detective controls by creating a monitoring framework:

  • AWS CloudTrail for comprehensive API activity logging and auditing to enable investigation of unauthorized access attempts and configuration changes.
  • AWS Config rules for bucket configuration. AWS Config rules or AWS Config conformance packs deployed for the entire organization can monitor S3 bucket configurations for compliance.
  • Security Hub findings for continuous assessment by aggregating findings and flagging non-compliant resources.
  • Amazon EventBridge rules for policy changes to detect and route S3 bucket policy modifications.
  • IAM Access Analyzer for external access review.
  • Regular compliance reporting, which can be automated through AWS Audit Manager.

Implement responsive controls by automating remediation where possible:

  • Security Hub and Systems Manager integration to automate incident response workflows.
  • Custom Lambda functions for specific use cases.
  • Integration with ITSM for human review when needed.
  • AWS Config remediation rules For example, the AWSConfigRemediation-ConfigureS3PublicAccessBlock runbook configures an AWS account’s S3 Block Public Access settings based on the values you specify in the runbook parameters.

The following table describes control types, what a basic implementation includes, and the services and methods used for advanced implementation.

Control type Basic implementation Advanced implementation
Preventative Documentation, peer reviews SCPs, RCPs, DPs, IAM policies, and S3 Block Public Access
Detective Security Hub, AWS Config rules Security Hub, AWS Config, and CloudWatch alerts
Responsive Manual remediation Auto-remediation through AWS Config, Systems Manager, EventBridge, and Lambda
Compliance One-time checks CIS/NIST mapping with Security Hub and automation of evidence collection and reporting using AWS Audit Manager
Automation Limited Full CI/CD Integration (for example, using CloudFormation or Terraform)
Cost optimization effort High (manual effort) Low (automation reduces overhead)

Scaling and management considerations

As your security and governance program matures, scaling these controls across a growing organization requires thoughtful management and automation. This section explores key considerations for effectively managing your security posture at scale, optimizing costs, and maintaining consistency across your AWS environment. Whether you’re expanding across multiple accounts, business units, or AWS Regions, these practices help you balance security requirements with operational efficiency and cost management.

Use AWS services effectively:

  • Consider deploying AWS Control Tower for consistent account setup and centrally deploying and managing controls at scale across multiple use cases and organizational units.
  • AWS Organizations can aid hierarchical policy management and the implementation of:
    • IAM policies for identity-based guardrails and permissions
    • SCPs for access guardrails
    • RCPs define permissions based on resource attributes
    • DPs to help facilitate consistent resource configurations across your organization
    • Tag policies for consistent resource categorization
    • Backup policies for data protection standards
    • AI service opt-out policies for data privacy requirements
    • Cost allocation tag policies to standardize cost attribution
    • Data residency policies to enforce regional restrictions
  • Implement resource governance through policy integration
    • For example, use Organizations tag policies to enforce a Confidential tag on S3 buckets storing personally identifiable information (PII). Combine this with SCPs that mandate AES-256 encryption for tagged buckets, overriding developer attempts to disable it.
    • Using backup policies to enforce retention rules (for example, Retention=7 years).
    • Use DPs to help maintain consistent security configurations across resources, such as enforcing encryption settings on Amazon Elastic Block Store (Amazon EBS) volumes or requiring specific security group rules.
  • Centralize logging and monitoring

Manage compliance exceptions:

  • Implement clear exception processes
  • Document and track approved exceptions
  • Establish regular periodic reviews of exceptions
  • Use time-bound approvals with automated expiration

Optimize costs:

  • Use periodic instead of continuous checking where appropriate
  • Implement targeted monitoring based on resource criticality
  • Use AWS Config recordings effectively
  • Balance automation costs against manual effort

Conclusion: Moving forward with control maturity

Implementing a comprehensive control framework is a journey, not a destination. Start from your organization’s current position, whether that’s with basic detective controls or a fresh implementation, and focus on progressive improvement rather than attempting to implement everything at once. Success comes from carefully documenting decisions about control implementation, regularly reviewing them, and using automation to reduce operational overhead while improving consistency. Progress can be measured through concrete metrics: reduced findings, faster remediation times, and increased automation.

Remember that the goal extends beyond better security—it’s about transforming security and governance from a reactive operation to a strategic enabler that provides real business value. This transformation manifests through reduced risk from systematic controls, improved operational efficiency through automation, and enhanced visibility and governance. Perhaps most importantly, it frees security teams to focus on strategic initiatives rather than routine operational tasks.

By following this approach, you can build a robust security and governance posture that not only protects your organization’s AWS environment but also supports business innovation and growth. The result is a security program that evolves alongside the business, enabling rather than hindering progress, while maintaining a strong approach that can scale with your organization’s needs.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS specializing in infrastructure security and compliance. He leads Technical Field Communities focused on security and compliance while contributing to AWS Well-Architected guidance. Before AWS, he helped clients across financial services, healthcare, and retail industries improve their security posture in hybrid environments. Outside of work, Luis enjoys staying active and culinary adventures.

Rodolfo Brenes

Rodolfo Brenes

Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

George'son Tib.

George’son Tib.

George’son is a Solutions Architect focused on Infrastructure Security at AWS, working with Enterprise customers in the Auto and Manufacturing Industry. He specializes in helping organizations build robust, automated control frameworks that enhance their security posture and drive operational efficiency.

Unlock new possibilities: AWS Organizations service control policy now supports full IAM language

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/unlock-new-possibilities-aws-organizations-service-control-policy-now-supports-full-iam-language/

Amazon Web Service (AWS) recently announced that AWS Organizations now offers full AWS Identity and Access Management (IAM) policy language support for service control policies (SCPs). With this feature, you can use conditions, individual resource Amazon Resource Names (ARNs), and the NotAction element with Allow statements. Additionally, you can now use wildcards at the beginning or middle of the Action element strings and implement the NotResource element in both Allow and Deny statements in SCPs. This feature is now available across AWS commercial and AWS GovCloud (US) Regions.

In this blog post, we walk through a set of newly supported SCP language capabilities that simplify permission management cases. These enhancements enable more intuitive and concise policy designs. We explore how these capabilities address past limitations to reduce operational overhead and improve policy readability. We also show what the previous implementation looked like and provide an example of how the new capability makes the intent clearer and implementation simpler.

Overview of the newly supported elements

The following table lists the supported SCP language elements along with their purpose and applicable effects. Elements and effects shown in bold indicate newly supported capabilities.

Element Purpose Supported effects
Version Specifies the language syntax rules to use for processing the policy. Allow, Deny
Statement Serves as the container for policy elements. You can have multiple statements in an SCP. Allow, Deny
Statement ID (Sid) (Optional) Provides a friendly name for the statement. Allow, Deny
Effect Defines whether the SCP statement allows or denies access to the IAM users and roles in an account. Allow, Deny
Action Specifies the AWS service and actions that the SCP allows or denies. Allow, Deny
NotAction Specifies the AWS service and actions that are exempt from the SCP. Used instead of the Action element. Allow, Deny
Resource Specifies the AWS resources that the SCP applies to. Allow, Deny
NotResource Specifies the AWS resources that are exempt from the SCP. Used instead of the Resource element. Allow, Deny
Condition Specifies the conditions for when the statement is in effect. Allow, Deny

Additionally, you can now use the wildcard characters * and ? anywhere in the Action or NotAction element. Previously, these wildcards were only allowed by themselves or at the end of an element. For example, all of the following are now valid:

  • "servicename:action*"
  • "servicename:*action"
  • "servicename:some*action"
  • "servicename:*"

Navigating new SCP language capabilities

Let’s explore recommended policy strategies and best practices by walking through some examples.

Using Deny with NotResource

You can use the NotResource element to apply a policy across resources except those explicitly listed. This is especially useful for implementing broad deny-by-default policies with scoped exceptions, simplifying policy structure while enforcing strong boundaries.

Example 1:

The goal of this example is to enforce a resource perimeter that blocks access to resources outside the organization, except for a defined set of service-owned resources.

  • Previous implementation: The policy used a tag-based approach to manage exceptions. It required tagging IAM principals with dp:exclude:resource:s3=true to grant access to external resources. This created operational overhead in tag management and introduced potential security risks if tags were incorrectly applied.
  • Improved implementation: With support for NotResource in Deny statements, the updated SCP uses a single, consolidated Deny statement denying the action except for a defined set of AWS-owned resources.
Policy structure before NotResource support Policy structure after NotResource support
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeterAWSResourcesS3",
      "Effect": "Deny",
      "Action": "s3:GetObject",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "aws:ResourceOrgID": "<my-org-id>",
          "aws:PrincipalTag/dp:exclude:resource:s3": "true"
        }
      }
    }
  ]
}

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EnforceResourcePerimeterAWSResources",
      "Effect": "Deny",
      "Action": "s3:GetObject",
      "NotResource": [
        "arn:aws:s3:::service-owned-bucket/*",
        "arn:aws:s3:::service-owned-bucket2/*"
      ],
      "Condition": {
        "StringNotEquals": {
          "aws:ResourceOrgID": "<org-id>"
        }      
       }
    }
  ]
}

Example 2:

This example denies access to Amazon Bedrock models except for one specific model.

  • Before this change: SCP relied on a broad permission baseline for AWS accounts within the organization by allowing access to Amazon Bedrock actions by default, while explicitly denying invocation of three specific models (examples: Deepseek, Anthropic, and meta). However, this approach requires continuous operational overhead to make sure policies are updated to deny access to newly added models to avoid exposure to potentially unwanted models.
  • Improved implementation: With support for NotResource in Deny statements, the updated SCP uses a single, consolidated Deny statement that denies actions except Amazon models.
Policy structure before NotResource support Policy structure after NotResource support
{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": "bedrock:*",
			"Resource": "*"
		},
		{
			"Effect": "Deny",
			"Action": [
				"bedrock:InvokeModel",
				"bedrock:InvokeModelWithResponseStream",
				"bedrock:PutFoundationModelEntitlement"
			],
			"Resource": [
				"arn:aws:bedrock:*::foundation-model/deepseek.*",
				"arn:aws:bedrock:*::foundation-model/anthropic.*",
				"arn:aws:bedrock:*::foundation-model/meta.*"
			]
		}
	]
}

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Effect": "Allow",
			"Action": "bedrock:*",
			"Resource": "*"
		},
		{
			"Sid": "Statement1",
			"Effect": "Deny",
			"Action": [
				"bedrock:InvokeModel",
				"bedrock:InvokeModelWithResponseStream",
				"bedrock:PutFoundationModelEntitlement"
			],
			"NotResource": [
				"arn:aws:bedrock:*::foundation-model/amazon.*"
			]
		}
	]
}

Using Allow with conditions

By using the Condition element, you can specify the circumstances under which a policy statement is in effect. While optional, this element is now supported in Allow statements within SCPs, enabling more precise and scalable access control.

Note: We recommend using explicit Deny statements when authoring SCPs in most cases. Using Deny statements help make sure that each control works independently and remains enforceable. Relying solely on allow statements and the implicit deny-by-default model can lead to unintended access, because broader or overlapping Allow statements can override more restrictive ones.

The following example allows access to specific AWS services in certain AWS Regions.

  • Before this change: The policy uses a single Allow statement under the Sid: AllowSpecificServices. It lists broad service-level actions (for example, "ec2:", "s3:", and so on) in the Action element and applies them across resources ("Resource": "*"). Because AWS SCPs operate under a deny-by-default model, this setup effectively permits actions across the listed services while implicitly denying access to other services not included. For example, an explicit Deny restricts actions outside us-east-1, us-west-2, and eu-central-1 using a Region condition.
  • Improved implementation: In the updated example, the policy allows the same services, but only when they are requested in specific Regions (for example, "us-east-1", "us-west-2", and "eu-central-1"). This is achieved using the aws:RequestedRegion condition key in the Allow statement. This enhancement allows organizations to retain basic Allow logic while introducing contextual boundaries—such as limiting access by Region, account, or resource tag—previously only possible with Deny conditions.

Note: We recommend using one broad Allow statement and multiple targeted Deny statements in your policies. Avoid writing additional Allow statements that might overlap, because doing so could lead to unintended access. The recommended approach is to start with a broad Allow statement and then use Deny statements to refine and restrict access as needed.

Policy structure before support for Allow with conditions Policy structure after support for Allow with conditions
{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"AllowSpecificServices",
         "Effect":"Allow",
         "Action":[
            "ec2:*",
            "s3:*",
            "rds:*",
            "lambda:*",
            "cloudformation:*",
            "iam:*",
            "cloudwatch:*"
         ],
         "Resource":"*"
      },
      {
         "Sid":"AllowAccessOnlyTo3Regions",
         "Effect":"Deny",
         "Action":"*",
         "Resource":"*",
         "Condition":{
            "StringNotEquals":{
               "aws:RequestedRegion":[
                  "us-east-1",
                  "us-west-2",
                  "eu-central-1"
               ]
            }
         }
      }
   ]
}

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowServicesBasedOnRegion",
      "Effect": "Allow",
      "Action": [
        "ec2:*",
        "s3:*",
        "rds:*",
        "lambda:*",
        "cloudformation:*",
        "iam:*",
        "cloudwatch:*"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:RequestedRegion": [
            "us-east-1",
            "us-west-2",
            "eu-central-1"
          ]
        }
      }
    }
  ]
}

Other newly supported elements

To bring SCPs to full IAM policy language support, additional elements are now supported. While technically valid, some of these constructs require additional considerations and testing in practice because of their potential for unintended access if not carefully managed.

Newly supported feature Important considerations
Action with wildcards (*, ?) Can help shorten policies but use with caution—new actions added by AWS will match existing wildcard patterns as designed, potentially granting unintended permissions.
NotAction with wildcards (*, ?) We recommend using NotAction with a Deny statement if you want to deny all actions except those listed, which helps future-proof your controls (for example, denying everything in Amazon EC2 except actions that don’t match “*vpn*”.
Allow with NotResource Limited use cases. While supported, Allow with NotResource can default to including all resources—potentially allowing access to new resources added later. Use with caution and prefer explicit Deny statements when possible.
Allow with NotAction Limited use cases. While supported, Allow with NotAction can unintentionally permit access to new actions added by AWS. Use with caution and prefer explicit Deny statements to maintain control as services evolve.
Allow with Resource other than wildcard “*”. When using Allow with specific resources (not "*"), make sure your policy design avoids conflicting or overlapping Allow statements. Start with a broad Allow, then use targeted Deny statements to restrict access—this helps prevent unintended access from overlapping Allow statements.

Validate your policies with IAM Access Analyzer

You can use AWS IAM Access Analyzer to validate your SCPs before applying them, using both policy validation and custom policy checks.

IAM Access Analyzer validates your policy against IAM policy grammar and best practices. You can view policy validation check findings that include security warnings, errors, general warnings, and suggestions. These findings provide actionable recommendations to help you author policies that are both functional and aligned with security best practices.

Custom policy checks are an IAM Access Analyzer capability that security teams can use to help them accurately and proactively identify critical permissions in their policies. Custom policy checks can determine whether a new version of a policy is more permissive than the previous version. They use automated reasoning—a form of static analysis—to provide a higher level of security assurance in the cloud.

Custom policy checks can be embedded into continuous integration and continuous delivery (CI/CD) pipelines, so that policies can be checked without being deployed. Developers can also run custom policy checks from their local development environments and receive fast feedback on whether the policies they are authoring comply with your organization’s security standards. For more information refer to introducing IAM Access Analyzer custom policy checks.

Conclusion

The latest enhancements to AWS service control policies improve policy expressiveness and precision while reducing operational effort. By enabling constructs like Allow with conditions and specific resource ARNs, supporting NotResource in Deny statements, and expanding wildcard flexibility, you can simplify your policies and avoid layered or complex policies to achieve your goals. These updates bring SCPs in parity with IAM policy capabilities and empower organizations to implement cleaner, more intuitive access controls. As a best practice, it’s important to use these capabilities carefully—especially wildcard use—to avoid unintended permissions as AWS services evolve. We also encourage the implementation of explicit Deny statements as a best practice and using Allow statements when needed.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Swara Gandhi

Swara Gandhi

Swara is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Niti Prasad

Niti Prasad

Niti is a Senior Security Solutions Architect supporting Strategic Accounts. She supports customers as they look to secure and govern their AWS environment. Her enthusiasm for security drives her to continuously explore innovative ways to help customers protect their cloud workloads.

A Complete Guide to Resource Sharing for AWS End User Messaging

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/a-complete-guide-to-resource-sharing-for-aws-end-user-messaging/

Introduction

Do you need to send SMS across multiple AWS accounts? Or have you ever wanted to use the same specific 10DLC phone number or branded Sender ID across those accounts? Perhaps your development team needs to test an application in a sandbox account using a production-ready number, or you’re migrating a workload to a new account and need to ensure your customer communications aren’t disrupted. Centralizing your messaging resources across accounts improves efficiency and branding, while lowering the risk in compliance gaps..

In this step-by-step guide, we will show how to solve this challenge by sharing your AWS End User Messaging resources across multiple AWS accounts using AWS Resource Access Manager (AWS RAM). By creating a single sharing account for your messaging resources—like phone numbers, Sender IDs, and opt-out lists—and securely sharing them with your other “consuming” accounts, you can build a more efficient, secure, and scalable communication platform.

Common Use Cases for Resource Sharing

Important: resource sharing with AWS RAM is a regional feature. You can only share resources with accounts within the same AWS Region where those resources are located.

Centralizing and sharing resources is a powerful pattern that addresses several common customer needs:

  • Testing in a Sandbox Environment: Allows development teams to test applications using production-ready phone numbers or Sender IDs in an isolated sandbox account, without giving them access to production configurations.
  • Simplified Registration and Onboarding: Share an existing pre-registered 10DLC number or Sender ID with a new account that has not yet completed its own registration process, enabling it to start sending messages more quickly.
  • Seamless Account Transitions: When migrating an application or workload to a new AWS account, you can share the existing origination identities. This makes certain that your phone numbers and Sender IDs remain consistent during the transition, preventing any disruption to your customer-facing communications.

This guide will walk you through the step-by-step process of sharing your AWS End User Messaging resources.

Shareable AWS End User Messaging Resources

You can share the following AWS End User Messaging resources using AWS RAM:

  • Phone Numbers: Share your dedicated short codes, 10DLCs, long codes, and toll-free numbers. This allows different accounts to send messages using a centralized pool of numbers.
  • Sender IDs: Share alphanumeric sender IDs to maintain consistent branding in one-way SMS messages across your accounts.
  • Opt-out Lists: Centralize your opt-out management to ensure regulatory compliance. When a user opts out of messaging from one account, they are opted out across all accounts using that shared list. This is especially powerful when used with pools, as you can associate a pool with a specific opt-out list, ensuring all numbers in that pool adhere to the same primary list. As a best practice, you should create and share a dedicated opt-out list rather than relying on the default list for each account.
  • Pools: Share your pools of phone numbers and sender IDs to manage origination identities at scale. Pools provide benefits like automatic failover and apply settings like opt-out lists or two-way SMS configurations to the entire pool.
    • Important: for a shared Opt-out list or pool to be functional, all of its member resources (the phone numbers and/or Sender IDs within it) must also be included in the same AWS RAM resource share.

Understanding AWS RAM Fundamentals

Before sharing your End User Messaging resources, it’s essential to understand the core concepts of AWS RAM.

  • Resource Share: This is the central component in AWS RAM. A resource share consists of three elements:
    • The resources to be shared (such as phone numbers, or opt-out lists).
    • The principals (AWS accounts, OUs, or an entire organization) with whom you are sharing.
    • The managed permissions that define what actions the principals can perform on the shared resources.

Important: The supported resources of AWS End User Messaging are shareable with AWS accounts, Organizations, and OUs, but not with individual AWS Identity and Access Management (IAM) roles or users. This restriction ensures that resource sharing remains at the account level, maintaining clear boundaries and simplifying access management for your End User Messaging infrastructure.

  • Sharing Account vs. Consuming Account:
    • The sharing account (or owner account) is the AWS account that owns the resources and creates the resource share.
    • When a principal (such as an AWS account) is granted access to a resource share, it becomes a consuming account. It can use the shared resources according to the permissions granted and pays for its own usage of those resources, not for the resources themselves. For example: The consuming account pays for the volume of SMS sent by a shared number but the sharing account pays for any fees associated with owning that actual number.
  • AWS Organizations Integration: While you can share resources with individual AWS accounts, the most powerful way to use AWS RAM is in conjunction with AWS Organizations. This service allows you to centrally manage and govern multiple AWS accounts under a single umbrella. When you enable sharing within your organization, you can share resources with all accounts in the organization, or with specific Organizational Units (OUs), seamlessly and without needing to send and accept individual invitations. This sharing is only possible between accounts that reside in the same AWS Region.
  • Managed Permissions: AWS RAM uses managed permissions to control access.
    • AWS managed permissions are predefined permission sets created and maintained by AWS for common use cases. For AWS End User Messaging, the key permission is AWSRAMDefaultPermissionSmsVoice, which allows consumers to use the resources for sending messages but not for deleting or modifying them.
    • Customer managed permissions can be created for more granular control over shared resources.
  • Resource-Based Policies: Behind the scenes, AWS RAM works by creating and managing resource-based policies for you. These policies are what actually grant the consuming accounts access to the shared resources.

To better illustrate these sharing models, the following diagrams show how a Sharing Account can share its AWS End User Messaging resources using different strategies:

Diagram 1: Direct Account-to-Account Sharing:

Diagram 2: Sharing with an Entire AWS Organization:

Diagram 3: Sharing with a Specific Organizational Unit (OU):

Prerequisites and Setup

For the following walkthrough, we will demonstrate how to configure the setup for Diagram 1: Direct Account-to-Account Sharing. However, the steps for managing and using the resource share are similar for all three scenarios. Before you begin, ensure your environment is set up correctly.

Note for AWS Organizations Users: When your account is managed by AWS Organizations, you can take advantage of that to share resources more easily. With or without Organizations, a user can share with individual accounts. However, if your account is in an organization, then you can share with individual accounts, or with all accounts in the organization or in an OU without having to enumerate each account.

If you plan to share resources using AWS Organizations (as shown in Diagram 2 or Diagram 3), you must complete the following prerequisite steps from your organization’s management account before creating a resource share:

1. Enable all features in your organization:

aws organizations enable-all-features

2. Enable resource sharing with AWS RAM: This creates the necessary service-linked role.

aws ram enable-sharing-with-aws-organization

1. Required IAM Permissions

The IAM user or role performing these actions needs permissions for both AWS RAM and AWS End User Messaging. The following policy grants the necessary permissions to manage resource shares.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RAMResourceShareManagement",
            "Effect": "Allow",
            "Action": [
                "ram:UpdateResourceShare",
                "ram:DeleteResourceShare",
                "ram:AssociateResourceShare",
                "ram:DisassociateResourceShare"
            ],
            "Resource": "arn:aws:ram:*:*:resource-share/*"
        },
        {
            "Sid": "DiscoveryAndCreationPermissions",
            "Effect": "Allow",
            "Action": [
                "ram:CreateResourceShare",
                "ram:GetResourceShares",
                "ram:ListResources",
                "organizations:ListAccounts",
                "organizations:DescribeOrganization",
                "pinpoint-sms-voice-v2:DescribePhoneNumbers",
                "pinpoint-sms-voice-v2:DescribeSenderIds",
                "pinpoint-sms-voice-v2:DescribeOptOutLists",
                "pinpoint-sms-voice-v2:DescribePools"
            ],
            "Resource": "*"
        }
    ]
}

Note on Least Privilege: This policy follows the security best practice of granting least privilege. The first statement scopes modification permissions to only AWS RAM resource shares. The second statement grants permissions for discovery actions (like Describe* and List*) and the ram:CreateResourceShare action, which require "Resource": "*" as they do not operate on a specific, pre-existing resource.

2. Regionality Requirement

Important Reminder: resource sharing with AWS RAM is a regional feature. You can only share resources with accounts within the same AWS Region where those resources are located.

For example, a resource in us-east-1 can only be shared with other accounts in us-east-1, regardless of where those accounts operate other resources. Ensure that the resources you intend to share and the accounts that you anticipate sharing with are each considering the same Region for this process.

Creating and Managing Resource Shares (Sharing Account Actions)

This section provides a step-by-step guide to sharing your resources using the AWS CLI. We will walk through creating a resource share, associating and disassociating resources, and checking the status of your shares.

Step 1: Create an Empty Resource Share

First, create the resource share. Think of this as an empty container. You will associate principals (the consuming accounts) and resources (the phone numbers, etc.) with this share.

In the command below, we will create a share named EUM-Shared-Resources for an external account.

# Create a resource share and grant default End User Messaging permissions # Replace 123456789012 with the consuming account's ID
aws ram create-resource-share \
    --name "EUM-Shared-Resources" \
    --principals "123456789012" \
    --permission-arns "arn:aws:ram::aws:permission/AWSRAMDefaultPermissionSmsVoice" \
    --allow-external-principals \
    --region us-east-1
  • --principals: Specify one or more AWS account IDs.
  • --allow-external-principals: This flag is required when sharing with accounts that are not part of your AWS Organization.

Expected Response: A successful command returns a JSON object describing the new resource share. Note that allowExternalPrincipals is now true.

{
    "resourceShare": {
        "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
        "name": "EUM-Shared-Resources",
        "owningAccountId": "111122223333",
        "allowExternalPrincipals": false,
        "status": "ACTIVE",
        "tags": [],
        "featureSet": "STANDARD"
    }
}

For the following sections and when specifying resource ARNs, ensure you’re using the correct format for AWS End User Messaging resources:

  • Phone numbers: arn:aws:sms-voice:region:account-id:phone-number/phonenumber-id
  • Sender IDs: arn:aws:sms-voice:region:account-id:sender-id/senderid
  • Opt-out lists: arn:aws:sms-voice:region:account-id:opt-out-list/optoutlist-id
  • Pools: arn:aws:sms-voice:region:account-id:pool/pool-id

Replace ‘region‘, ‘account-id‘, and the specific resource IDs with your actual values.

Step 2: Associate Resources with the Share

Now that you have your “container,” you can add resources to it. The associate-resource-share command links one or more of your End User Messaging resources to the share you just created, making them available to the principals.

# Define the ARN of the resource share from the previous step
RESOURCE_SHARE_ARN="arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-111111111111"

# Associate a phone number and a pool with the share # Replace the resource-arns with your actual resource ARNs
aws ram associate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns \
        "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
        "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --region us-east-1

Expected Response: A successful association returns a JSON object confirming the association and showing its status. The status will initially be ASSOCIATING and will transition to ASSOCIATED once complete.

Note: The association process is asynchronous. We’ll show you how to verify the completion status in the next step using the get-resource-shares and list-resources commands. It’s important to confirm the status has changed to ASSOCIATED before attempting to use the shared resources.

Step 3: Verify the Status and contents of the Share

Before making changes, it’s good practice to verify what’s in the share. Use get-resource-shares to check the status and list-resources to see the contents. This process helps ensure that all intended resources are properly associated and accessible to the principals you’ve designated.

# Verify the association status is ASSOCIATED
aws ram get-resource-shares \
    --resource-owner SELF \
    --name "EUM-Shared-Resources" \
    --association-status ASSOCIATED \
    --region us-east-1

Expected Response: If the command returns no results, wait a few moments and try again. The association process is typically quick but can sometimes take up to a few minutes.

{
    "resourceShares": [
        {
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/12345678-abcd-1234-efgh-111122223333",
            "name": "EUM-Shared-Resources",
            "owningAccountId": "111122223333",
            "allowExternalPrincipals": true,
            "status": "ACTIVE",
            "creationTime": "2023-07-01T12:00:00.000Z",
            "lastUpdatedTime": "2023-07-01T12:00:00.000Z",
            "featureSet": "STANDARD"
        }
    ]
}

Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.

Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.

# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1

Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.

# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1

Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.

{
    "resources": [
        {
            "arn": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "type": "sms-voice:PhoneNumber",
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "status": "AVAILABLE"
        },
        {
            "arn": "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5",
            "type": "sms-voice:Pool",
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "status": "AVAILABLE"
        }
    ]
}

Step 4: Disassociate Specific Resources from the Share

To stop sharing a specific resource, you use the disassociate-resource-share command. You must provide the ARN of the resource you wish to remove. This gives you granular control, allowing you to remove one resource while continuing to share others.

# Disassociate only the phone number from the share
aws ram disassociate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --region us-east-1

Expected Response: The response will be nearly identical to the associate response, confirming the disassociation request. The status will be DISASSOCIATING.

{
    "resourceShareAssociations": [
        {
            "resourceShareArn": "arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-example11111",
            "associatedEntity": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "associationType": "RESOURCE",
            "status": "DISASSOCIATING",
            "external": false
        }
    ]
}

How to Use Shared Resources

Once resources are shared, users in the consuming accounts can discover and use them for sending messages.

Step 1: Discovering Shared Resources

From a consuming account, you can list resources that have been shared with you by using the --filters parameter in the describe-* commands.

Note: Shared resources are discoverable via the AWS CLI and SDKs but will not appear in the AWS Management Console of the consuming account. This is expected behavior, as the resources are owned by the sharing account.

# List phone numbers shared with your account
aws pinpoint-sms-voice-v2 describe-phone-numbers \
    --filters Name=shared-with-me,Values=true \
    --region us-east-1
# List sender IDs shared with your account
aws pinpoint-sms-voice-v2 describe-sender-ids \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List pools shared with your account
aws pinpoint-sms-voice-v2 describe-pools \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List shared opt-out lists with region specification
aws pinpoint-sms-voice-v2 describe-opt-out-lists \
--filters Name=shared-with-me,Values=true \
--region us-east-1

Expected Response: The command returns a JSON object listing the shared resources, including their ARNs, which you will need for sending messages.

{
    "PhoneNumbers": [
        {
            "PhoneNumberArn": "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4",
            "PhoneNumberId": "phonenumber-a1b2c3d4",
            "PhoneNumber": "+12065550100",
            "Status": "ACTIVE",
            "MessageType": "TRANSACTIONAL",
            "TwoWayEnabled": true,
            "CreatedTimestamp": "2023-10-26T14:34:56.123Z"
        }
    ]
}

Step 2: Sending Messages with Shared Resources

Important: When using shared resources, consuming accounts must specify the full ARN of the shared resource in API calls. This differs from resource owners, who can use either the resource ID, ARN, or the number directly. You can specify the ARN of an individual phone number or a pool as the origination-identity.

# Send an SMS using a shared Phone Number ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --message-body "Hello from a shared number!" \
    --region us-east-1

# Send an SMS using a shared Pool ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --message-body "Hello from a shared pool!" \
    --region us-east-1

Expected Response: A successful send-text-message call will return a MessageId, which confirms that the service has accepted the message for delivery.

{
    "MessageId": "a1b2c3d4-5678-90ab-cdef-example22222"
}

Message Delivery Reporting:

Once a message is sent, understanding its delivery status is crucial for ensuring your communications are effective. AWS End User Messaging provides several mechanisms for tracking message delivery, giving you a multi-layered approach to reporting.

Delivery Receipts (DLRs):

For traditional, carrier-provided Delivery Receipts (DLRs), which can sometimes take up to 72 hours to be returned, you must configure an event destination. This is the most common method for confirming that a message has reached the recipient’s handset, and is achieved through a Configuration Set.

For shared resources:

  • The configuration set must be created and managed in the sharing account.
  • The consuming account must then reference the ARN of the configuration set when sending messages.
# Example for consuming account
aws pinpoint-sms-voice-v2 send-text-message 
    --destination-phone-number "+12065550199" 
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" 
    --message-body "Hello from a shared number!" 
    --configuration-set-name "arn:aws:sms-voice:us-east-1:111122223333:configuration-set/MyConfigSet" 
    --region us-east-1

For a detailed walkthrough, see our companion blog post, How to Send SMS Using Configuration Sets with AWS End User Messaging.

Message Feedback:

For more immediate, application-driven insights, you can use the Message Feedback feature. This allows you to programmatically mark messages as “delivered” based on a user’s action, such as using a one-time password (OTP) or clicking a link in the message. This provides a real-time confirmation loop that is independent of carrier DLRs.

Amazon CloudWatch:

To monitor these events at scale, you can stream them to Amazon CloudWatch Logs to track key performance indicators like the number of messages sent and delivered, and to set up alerts based on your specific business needs.

To set up comprehensive reporting:

  1. Configure an event destination for DLRs and detailed status events.
  2. Set up CloudWatch dashboards and alerts for ongoing monitoring.

This multi-layered approach provides both immediate feedback and long-term delivery insights, allowing you to optimize your messaging strategy and quickly identify potential delivery issues.

Troubleshooting Common Issues

  • Permission Denied Errors: If a consuming account cannot access a shared resource, verify that the consuming account’s IAM policies include the necessary permissions. Here’s an example policy:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "pinpoint-sms-voice-v2:SendTextMessage",
                "pinpoint-sms-voice-v2:SendVoiceMessage",
                "pinpoint-sms-voice-v2:DescribePhoneNumbers",
                "pinpoint-sms-voice-v2:DescribeSenderIds",
                "pinpoint-sms-voice-v2:DescribeOptOutLists",
                "pinpoint-sms-voice-v2:DescribePools"
            ],
            "Resource": "*"
        }
    ]
}
  • Resource Not Visible: Remember that shared resources do not appear in the consuming account’s AWS Management Console. If the describe-* commands with the shared-with-me filter return no results, ensure the resource share status is ACTIVE in the sharing account.
    • If sharing via AWS Organizations, confirm the consuming account is correctly placed in the specified OU. You can find more information on managing OUs in the AWS Organizations User Guide.
  • CLI Command Fails: If a command fails with a “not found” or “invalid parameter” error, it is often due to an incorrect ARN. Double-check that the ARNs for resources, principals, and the resource share itself are correct. A Permission Denied error, on the other hand, points to an IAM policy issue..

Best Practices and Considerations

  • Security: Always follow the principle of least privilege. Use AWS managed permissions like AWSRAMDefaultPermissionSmsVoice where possible and create customer-managed permissions only for specific, granular requirements.
  • Cost: The sharing account is billed for provisioning the resources (e.g., the monthly cost of a phone number). Consuming accounts are billed for their usage of those shared resources (e.g., the cost per message sent). There are no additional costs for using AWS RAM.
  • Throughput and Quotas: Resource throughput quotas (e.g., messages per second) are shared along with the resource. High volume sending from multiple consuming accounts using the same shared number or pool, could collectively hit the service quota, which may result in throttling. Plan your usage accordingly or request quota increases if necessary.

Conclusion

This guide has equipped you to centralize your AWS End User Messaging resources using AWS Resource Access Manager. By implementing this strategy, you can directly address the common challenges of a multi-account environment: maintaining consistent branding with shared Sender IDs, ensuring comprehensive compliance with centralized opt-out lists, and reducing operational overhead by managing resources in one place.

We have walked through the entire lifecycle, from the initial prerequisites in AWS Organizations and IAM, to the step-by-step CLI commands for creating shares, associating resources, and enabling consuming accounts to use them. By applying these techniques and keeping the best practices for security and throughput in mind, you are now able to build a more efficient, secure, and scalable communication platform across your entire AWS ecosystem.

Managing Amazon Q Developer Profiles and Customizations in Large Organizations

Post Syndicated from Marco Frattallone original https://aws.amazon.com/blogs/devops/managing-amazon-q-developer-profiles-and-customizations-in-large-organizations/

As organizations scale their development efforts, AI coding assistants that understand organization-specific patterns and standards lead to more efficient development processes and higher quality software delivery. Amazon Q Developer Pro helps address this challenge by allowing organizations to customize the AI assistant with their proprietary code and development practices. Through Amazon Q Developer profiles, teams can efficiently manage access to Amazon Q customizations across different regions and AWS Identity Centers.

In this post, we will explore different approaches for implementing and managing Amazon Q Developer profiles and Amazon Q customizations across large organizations. Using an example with multiple business units, we will explore methods for managing access controls and customization governance while addressing security and compliance requirements.

Amazon Q customization is now available in both the US East (N. Virginia) and EU Central (Frankfurt) regions, giving teams more flexibility to create and deploy customizations closer to their operational hubs while meeting regional data residency requirements.

This blog is not intended to provide recommendations on how to structure your AWS accounts or divide Q Developer subscriptions. Rather, our aim is to explore the full capabilities of Q Developer Customizations in a comprehensive scenario that shows the current art of the possible.

A distributed Amazon Q Developer Pro subscriptions scenario

The following diagram illustrates a sample AWS Organizations structure with a Management Account and four Organizational Units (OUs). This is a common enterprise scenario with three business units, each business unit requiring their own Amazon Q Developer Pro subscription and customizations.

Diagram showing AWS Organizations structure with a Management Account at the top, containing AWS Organizations, IAM Identity Center, Amazon Q, Management Customizations, and AWS Cost & Usage Report. Below are four Organizational Units (OUs): Infrastructure, Alpha, Bravo, and Charlie. The structure illustrates the hierarchical relationship and resource allocation across different OUs and regions within an AWS organization.

Figure 1: AWS Organizations Structure and Resource Hierarchy

The Infrastructure OU has a Delegated Admin Account with delegated access to the AWS IAM Identity Center. There are three additional OUs: Alpha, Bravo, and Charlie, each with at least one Amazon Q Developer Pro subscription. Alpha account has Amazon Q Developer subscriptions both in US East (N. Virginia) and EU Central (Frankfurt) region.

Think of each business unit as its own ecosystem within your organization. When you provide dedicated Q Developer Pro subscriptions to different OUs, you’re essentially giving each unit its own personalized AI assistant. This separation is valuable because it allows each team to work independently while maintaining their specific requirements and workflows.

The Charlie OU maintains its own account instance of IAM Identity Center for Amazon Q Developer Pro. In most cases, we recommend using an organization instance of IAM Identity Center with Amazon Q Developer Pro, there are a few situations where member account instances might make sense, for example: when you do not have a single identity provider, or when you haven’t yet decided to deploy it to the whole organization and want to use Amazon Q just for the AWS account you control.

Note: When a developer has a user within an Amazon Q profile tied to two different IAM Identity Center instances (Bravo and Charlie), they will have two user subscriptions and be billed twice. However, if they belong to two different Amazon Q profiles in two different accounts (Alpha and Bravo) but under the same IAM Identity Center, they will only be billed once.

In our example, the Charlie OU requires additional operational overhead in managing separate credentials and authentication flows. Additionally, the dashboard and administrative settings will only be associated with users and groups within this account.
From an administrative perspective, instead of trying to manage one centralized configuration that attempts to serve everyone’s needs, you can distribute administration to each business unit and delegate responsibility to individual teams.

It’s like having different specialized departments in a hospital – while they’re all part of the same organization and can work together when needed, each department has its own specialized tools and protocols that help them perform their specific functions more effectively.

A strategic approach to Customizations through Q Developer profiles

A diagram illustrating the structure of an AWS IAM Identity Center organization with multiple Amazon Q Developer Pro subscriptions and customizations. Each Q Developer Pro Subscription has its own set of users representing developers. Team orange developers have access to Alpha Q Subscription and customizations, Team blue developers have access to Alpha, Bravo and Charlie Q Subscription and customizations, Team Grey developers have only access to Bravo Subscription and customizations. The organization has also an AWS IAM Identity Center instance, with separate Amazon Q Developer Pro subscription and customizations. Team bravo developers are duplicated between the two IAM Identity Centers.

Figure 2 Developers association to Amazon Q Developer Pro Subscriptions, Customizations and IAM Identity Centers

Amazon Q Developer profiles are the way developers connect to different Amazon Q Developer subscriptions through their IDE. Each profile represents a unique combination of an Amazon Q Developer subscription and its associated customizations. After authentication, developers can simply select or switch between profiles in their IDE to access different customizations.

Let’s walk through some scenarios in this architecture.

Scenario 1 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account

Developers from the Orange team with access to Alpha account customizations can configure two different Amazon Q Developer profiles in their IDE:

  • A “US Profile” connected to the US East subscription in the Alpha account
  • An “EU Profile” connected to the EU Central subscription in the Alpha account

Switching between different sets of customizations involves selecting the relevant profile within their IDE.

Screenshot of IDE interface showing the Amazon Q Developer customizations panel. Developer switch between US and EU Profiles and their customizations

Figure 3 IDE showing customizations available for Team Orange developers switching between US and EU Profile and their customizations

Note: While developers can access multiple customizations through different Amazon Q Developer profiles, they only incur a single user subscription cost since they are using the organization instance of IAM Identity Center. This is because the subscription is tied to their user identity in the IAM Identity Center organization instance, not to the number of profiles or customizations they access.

Scenario 2 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account
Similarly, developers from the Blue team can also configure multiple profiles:

  • One profile for accessing Alpha and Bravo customizations through the management account AWS IAM Identity Center instance
  • A separate profile for accessing Charlie customizations through the AWS IAM Identity Center member account Instance

When developers have access to multiple customizations within the same IAM Identity Center configuration and region, they can switch between profiles in their IDE without requiring reauthentication.

Screenshot of IDE interface showing the Amazon Q Developer customizations panel. When authenticated through the AWS IAM Identity Center Organization, Blue developers can see both Alpha and Bravo customizations.

Figure 4 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Organization

However, as demonstrated in the blue developers’ case, switching between profiles that use different IAM Identity Center configurations (Organization vs Account Instance) still requires reauthentication.

Note: In this scenario, developers will incur two separate user subscription charges since they are accessing customizations through two different IAM Identity Center configurations (organization and account instance). As mentioned above, this scenario is not recommended except for situations it might make sense and is shown here purely to illustrate how the authentication and profile switching mechanisms work across different IAM Identity Center configurations.

Screenshot of IDE interface showing the Amazon Q Developer customizations panel. When authenticated through the AWS IAM Identity Center Instance, Blue developers can see only Charlie customizations.

Figure 5 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Account Instance

One scenario for creating code customizations specific to each profile is that the developers on the Alpha team might need Q to understand specific libraries and internal coding conventions for Java, while Bravo team developers might need Q to be well-versed in your proprietary technologies and development standards with Python. With separate profiles and customizations, each team gets their own “flavored” version of Q that understands their context.

For Blue developers who have access to Alpha, Bravo and Charlie customizations, they need to set up separate profiles since these customizations belong to different IAM Identity Center configurations and AWS Regions. Switching between these profiles requires reauthentication due to the different IAM Identity Center configurations involved.

Developer Team AWS IAM Identity Center Customizations
Orange Organization instance Alpha customizations in US East (N. Virginia)
Alpha customizations in EU Central (Frankfurt)
Blue Organization instance Alpha customizations in US East (N. Virginia)
Bravo customizations
Account instance Charlie customizations
Grey Organization instance Bravo customizations

You can manage access to specific Amazon Q Developer Pro customizations by adding selected users and groups who already have access to Amazon Q Developer Pro subscriptions within the same Identity Center. This granular access control allows you to create targeted customizations that are only accessible to specific team members or groups within your organization.

Conclusion

In this post, we explored comprehensive strategies for implementing Amazon Q Developer customizations across large organizations. We demonstrated how Amazon Q Developer profiles provide a flexible way to manage access to different customizations across AWS regions and IAM Identity Center configurations. By integrating proprietary code repositories, establishing customization governance, and implementing continuous feedback loops, enterprises can maximize the value of their AI-powered development assistant while maintaining code quality and development standards.

The path forward depends on where you are in your Amazon Q Developer customization journey. If you’re just starting, begin with a clear assessment of your codebase and map out your customization approach before implementation. For existing users, review your current customizations and profile configurations to identify optimization opportunities.

In both cases, implement the customization governance we discussed, tailoring them to your specific development patterns and team structures. Remember that customization evolves with your codebase – regular refinements help ensure your AI assistant remains effective as your applications grow and development practices mature. Whether you’re new to Amazon Q Developer customizations or optimizing existing implementations, these practices can help develop an AI assistant that truly understands and aligns with your organization’s unique development environment.

Ready to get started? Visit the Amazon Q Developer guide to learn more about setting up profiles and customizations for your organization. If you need help planning your customization strategy, contact your AWS account team or find an AWS Partner in the AWS Partner Network.

About the authors:

Marco Frattallone

Marco Frattallone is a Senior Technical Account Manager at AWS focused on supporting Partners. He works closely with Partners to help them build, deploy, and optimize their solutions on AWS, providing guidance and leveraging best practices. Marco is passionate about technology and enables Partners stay at the forefront of innovation. Outside work, he enjoys outdoor cycling, sailing, and exploring new cultures.

Francesco Martini

Francesco Martini is a Senior Technical Account Manager at AWS. He helps AWS customers build reliable and cost-effective systems and achieve operational excellence while running workloads on AWS. He is a builder and a technology enthusiast with a background as a full-stack developer. He is passionate about sports in general, especially soccer and tennis.

AWS Backup adds new Multi-party approval for logically air-gapped vaults

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-backup-adds-new-multi-party-approval-for-logically-air-gapped-vaults/

Today, we’re announcing the general availability of a new capability that integrates AWS Backup logically air-gapped vaults with Multi-party approval to provide access to your backups even when your AWS account is inaccessible due to inadvertent or malicious events. AWS Backup is a fully managed service that centralizes and automates data protection across AWS services and hybrid workloads. It provides core data protection features, ransomware recovery capabilities, and compliance insights and analytics for data protection policies and operations.

As a backup administrator, you use AWS Backup logically air-gapped vaults to securely share backups across accounts and organizations, logically isolate your backup storage, and support direct restore to help reduce recovery time following an inadvertent or malicious event. However, if a bad or unintended actor gains root access to your backup account or the management account of your organization, your backups suddenly become inaccessible, even though they’re still safely stored in the logically air-gapped vault. While traditional account recovery involved working through support channels, AWS Backup with Multi-party approval delivers immediate access to recovery tools, empowering you with faster resolution times and greater control over your recovery timeline.

Multi-party approval for AWS Backup logically air-gapped vaults adds an additional layer of protection for you to recover your application data even when your AWS account becomes completely inaccessible. Using Multi-party approval, you can create approval teams which consist of highly trusted individuals in your organization, then associate them with your logically air-gapped vault. If you get locked out of your AWS accounts due to inadvertent or malicious actions, you can request your own approval team to authorize sharing of your vault from any account, even those outside your AWS Organizations account. Once approved, you gain authorized access to your backups and can begin your recovery process.

How it works
Multi-party approval for AWS Backup logically air-gapped vaults combines the security of logically air-gapped vaults with the governance of Multi-party approval to create a recovery mechanism that works even when your AWS account is compromised. Here’s how it works:

1. Approval team creation
First, you create an approval team in your AWS Organizations management account. If the management account is new, first create an AWS Identity and Access Management (IAM) Identity Center instance before creating the approval team. The approval team consists of trusted individuals (IAM Identity Center users) who will be authorized to approve vault sharing requests. Each approver receives an invitation to join the approval team through a new Approval portal.

2. Vault association
When your approval team is active, you share it with accounts that own logically air-gapped vaults using AWS Resource Access Manager (AWS RAM) to safeguard against requests for approval from arbitrary accounts. Backup administrators can then associate this approval team with new or existing logically air-gapped vaults.

3. Protection against compromise
If your AWS account becomes compromised or inaccessible, you can request access to your backups from a different account (a clean recovery account). This request includes the Amazon Resource Name (ARN) of the logically air-gapped vault in the format arn:aws:backup:<region>:<account>:backup-vault:<name> and an optional vault name and comment.

4. Multi-party approval
The request is sent to the approval team, who review it through the approval portal. When the minimum required number of approvers authorize the request, the vault is automatically shared with the requesting account. All requests and approvals are comprehensively logged in AWS CloudTrail.

5. Recovery process
With access granted, you can immediately start restoring or copying your data in the new recovery account without waiting for your compromised account to be remediated.

This approach provides an entirely separate authentication path to access and recover your backups, completely independent of your AWS account credentials. Even if the bad actor has root access to your account, they can’t prevent the approval team-based recovery process.

1. Create a new logically air-gapped vault
To create a new logically air-gapped vault, provide a name, tags (optional), and vault lock properties.

2. Assign an approval team
When the vault has been created, choose Assign approval team to assign it with an existing approval team.

Choose an existing approval team from the drop-down menu then select Submit to finalize the assignment.

Now your approval team is assigned to your logically air-gapped vault.

Good to know
It’s essential to test your recovery process before an actual emergency:

  1. From a different AWS account, use the AWS Backup console or API to request sharing of your logically air-gapped vault by providing the vault ID and ARN.
  2. Request approval of your request from the approval team.
  3. Once approved, verify that you can access and restore backups from the vault in your testing account.

As a best practice, monitor the health of your approval team regularly using AWS Backup Audit Manager to ensure they have sufficient active participants to meet your approval threshold.

Multi-party approval for enhanced cloud governance
Today, we’re also announcing the general availability of a new capability that AWS account administrators can use to add Multi-party approval to their product offerings. As highlighted in this post, AWS Backup is the first service to integrate this capability. With Multi-party approval, administrators can enable application owners to guard sensitive service operations with a distributed review process.

Good to know
Multi-party approval provides several significant security advantages:

  • Distributed decision-making, eliminating single points of failure
  • Full auditability through AWS CloudTrail integration
  • Protection against compromised credentials
  • Formal governance for compliance-sensitive operations
  • Consistent approval experience across integrated services

Now available

Multi-party approval is available today in all AWS Regions where AWS Organizations is available. Multi-party approval for AWS Backup logically air-gapped vaults is available in all AWS Regions where AWS Backup is available.

– Veliswa.

How to import existing AWS Organizations SCPs and RCPs to CloudFormation

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/how-to-import-existing-aws-organizations-scps-and-rcps-to-cloudformation/

Many AWS Organizations customers begin by creating and manually applying service control policies (SCPs) and resource control policies (RCPs) through the AWS Management Console or AWS Command Line Interface (AWS CLI) when they first set up their environments. However, as the organization grows and the number of policies increases, this manual approach can become cumbersome. It can result in limited visibility into all implemented SCPs and RCPs, the targets they’re attached to (such as accounts, organizational units (OUs), or nested OUs), and the ability to manage updates effectively. Without clear visibility and proper access controls, it becomes challenging to track who’s making changes and how they are being made.

Importing existing SCPs and RCPs into AWS CloudFormation can help streamline the management of your policies by enabling history tracking, policy validation through CloudFormation Hooks, and rollback capabilities. You can also sync stacks with source code stored in a Git repository with Git sync. With Git sync, you can use pull requests and version tracking to configure, deploy, and update your CloudFormation stacks from a centralized location. When you commit changes to the template or the deployment file, CloudFormation automatically updates the stack.

In this post, I provide a solution to import existing SCPs and RCPs into AWS CloudFormation templates using the CloudFormation infrastructure as code generator (IaC generator). By using the IaC generator, you can automate the management of your SCPs and RCPs at scale.

Important: Only existing policies are brought into CloudFormation; policies are not recreated.

Solution overview

The solution in this post includes a command line tool for discovering SCPs and RCPs in your organization and automating policy import into CloudFormation templates. The following figure shows the end-to-end flow:

Figure 1: Solution overview

Figure 1: Solution overview

The end-to-end flow shown in the preceding figure includes:

  1. Run the tool: The tool automates the following steps and can be run in the management account or delegated administrator account.
    1. Identify SCPs and RCPs in the organization: The tool begins by making API calls to the Organizations service to retrieve the policies in your environment. It then provides a count of the total number of SCPs and RCPs present.
    2. Identify AWS Control Tower SCPs and RCPs and policies without targets:
      1. AWS Control Tower SCPs and RCPs: The tool checks for SCPs and RCPs created by AWS Control Tower and lists them in the output for your review.
        • SCPs are identified by the aws-guardrails- prefix in their policy names.
        • RCPs are identified by the AWSControlTower-Controls- prefix in their policy names.
      2. Policies with no targets: The tool also identifies SCPs and RCPs that aren’t attached to an organizational unit (OU), account, or root and lists them. These policies might be redundant or need reassignment.
    3. CloudFormation IaC generator scan: At this stage, you will be prompted to confirm whether you want to import the policies to the CloudFormation templates using CloudFormation resource scan. If you select yes, the tool will initiate a CloudFormation resource scan using IaC generator to get details about the policies including policy name, targets, policy tags, and so on.
    4. Create template from scanned policy resources: The tool generates CloudFormation template with the policy resources. The template will include the policies without targets (if any).
  2. Review process: After the template is generated, it’s recommended that you preview the template using IaC generator from the CloudFormation console. We recommend viewing the template resource section to verify and adjust the generated templates as needed (step 11 of the solution deployment).
  3. Create CloudFormation stacks with the generated templates: After reviewing the templates, import them into CloudFormation stacks for deployment. It’s important to note that only existing policies are brought into CloudFormation—policies aren’t recreated. The templates reflect the current policies and policy attributes.

Consideration before implementing the solution

There are some considerations that you need to keep in mind before implementing the solution.

  • If you have enabled the AWS Organizations policy management delegation, you should run this solution from the delegated administrator account. Otherwise, you can run the solution using the management account.

    Note: Delegating management of organizations policies to a delegated administrator member account is recommended best practice.

  • AWS Control Tower SCPs and RCPs (with or without targets) won’t be imported to the CloudFormation templates because they should be managed using AWS Control Tower. Changes made to AWS Control Tower resources outside of AWS Control Tower can cause drift and affect AWS Control Tower functionality in unpredictable ways.
  • FullAWSAccess SCP and RCPFullAWSAccess RCP are AWS managed policies that won’t be imported to CloudFormation because CloudFormation stacks do not allow importing AWS managed resources.
  • You might see multiple CloudFormation templates created if you exceed the CloudFormation template size quotas. To help ensure smooth creation, the tool is designed to automatically split the content into multiple templates if necessary, allowing you to stay within the quotas while still accommodating the imported content.
  • Note that the generated templates have the following attributes set by default.
    • Deletion policy: Set to Retain. This enables persisting the policies even when their related stack is deleted.
    • Update Replace policy: Set to Delete. This enables deletion of the physical ID associated with the policy when the policy is updated.

Solution deployment

Now that you understand the solution and know the considerations to keep in mind, you’re ready to deploy the solution.

  1. Clone the solution repository.
    git clone https://github.com/aws-samples/sample-tool-for-importing-existing-AWS-SCPs-and-RCPs
    

  2. Navigate to the directory of the cloned repository.
    cd sample-tool-for-importing-existing-AWS-SCPs-and-RCPs/
    

  3. Install the solution (Python 3.10+ is supported)
    pip install .
    

  4. If you want to use a particular AWS Identity and Access Management (IAM) principal to run this tool, create a profile in ~./aws/config using an IAM principal from your AWS Organizations management account. If you have delegated policy management to a member account, make sure that you use the IAM principal from the delegated administrator account. 

    Note: The IAM principal will need to have the following permissions to be able to successfully run the tool.

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "VisualEditor0",
                "Effect": "Allow",
                "Action": [
                    "organizations:Describe*",
                    "organizations:List*",
                    "cloudformation:Describe*",
                    "cloudformation:Detect*",
                    "cloudformation:Estimate*",
                    "cloudformation:Get*",
                    "cloudformation:List*",
                    "cloudformation:CreateGeneratedTemplate",
                    "cloudformation:StartResourceScan",
                    "cloudformation:UpdateGeneratedTemplate",
                    "cloudformation:CreateStack",
                    "cloudformation:DeleteStack",
                    "cloudformation:UpdateStack",
                    "cloudformation:DeleteGeneratedTemplate"
                ],
                "Resource": "*"
            }
        ]
    }
    

  5. You can run the tool specifying a profile name as a command line argument. Use the following command, replacing <profile_name> with the name of the profile you created in step 4. If you do not specify a profile, the default profile from the file ~./aws/config will be used.
    policy-importer --profile <profile_name>
    

  6. After the preceding command is executed, you will see an output displaying the total number of SCPs and RCPs found in the organization. The output will also list AWS Control Tower managed policies as INFO, in addition to policies without targets as a WARNING. At this point, you can enter Yes to proceed with scanning to import the policies, or enter No if you want to exit.

    Note: If policies without targets are detected, we recommend stopping at this point. Either delete the policies without targets or assign appropriate targets to them. You can then rerun the tool from step 5. If you proceed without addressing the policies without targets, be aware that these policies will also be included in the CloudFormation template.

    Figure 2: Terminal view with policies identified in the organization

    Figure 2: Terminal view with policies identified in the organization

  7. If you enter Yes, the CloudFormation IaC resource scan will begin immediately. You will see the resource scan ID Amazon Resource Name (ARN) displayed.

    Note: A scan can take up to 10 minutes for every 1,000 resources.

    Figure 3: Terminal view with AWS CloudFormation resource scan details

    Figure 3: Terminal view with AWS CloudFormation resource scan details

  8. You can also review the scan progress from the IaC generator page of the CloudFormation console as shown in the following figure. To get to the IaC generator page, go to the CloudFormation console and choose IaC generator from the navigation pane.
    Figure 4: View the scan summary in the CloudFormation console to track progress

    Figure 4: View the scan summary in the CloudFormation console to track progress

  9. Upon completion of the scan, the template generation process will be initiated.
    Figure 5: Terminal view showing CloudFormation template being created

    Figure 5: Terminal view showing CloudFormation template being created

  10. After the template creation is finished, sign in to the AWS CloudFormation IaC console. Choose the Templates tab to review the generated templates and verify that they align with your requirements.
    Figure 6: View CloudFormation templates in the console

    Figure 6: View CloudFormation templates in the console

  11. You can review the policies added to a template by selecting a template name.
    Figure 7: Review policies included in the template

    Figure 7: Review policies included in the template

  12. When satisfied, you can proceed to import the templates into CloudFormation stacks for deployment by selecting Import to stack.
    Figure 8: Import a template into the CloudFormation stack

    Figure 8: Import a template into the CloudFormation stack

  13. Follow the prompts to create a stack.
    Figure 9: AWS CloudFormation stack example

    Figure 9: AWS CloudFormation stack example

  14. The tool automatically creates a folder named Policies in your current directory and downloads the generated templates.

    Note: If you encounter errors, check the recommended solutions for common issues.

As shown in the following figure, there are two recommended next steps.

Figure 10: Solution overview including recommended next steps

Figure 10: Solution overview including recommended next steps

After the existing policies are imported into a CloudFormation stack, we recommend storing your CloudFormation templates in a private Git repository. You can use the Policies folder that was automatically created by the tool in the current local directory with the generated templates downloaded and set up a continuous integration and delivery (CI/CD) pipeline to efficiently manage the imported policies.

By using a Git repository, you can use version control features like pull requests, branch management, and history tracking. This approach allows your team to efficiently review, update, and deploy policies with better collaboration and control. You can also create a CI/CD pipeline to automate the deployment of changes to your CloudFormation stacks, helping to ensure that updates are consistent and reliable.

We also recommend incorporating CloudFormation Hooks in your environment. CloudFormation Hooks can help validate policies (and other resources) against best practices, to help ensure that they adhere to the correct syntax, follow security best practices, and minimize potential vulnerabilities.

Related resources:

Conclusion

Importing existing AWS Organizations service control policies (SCPs) and resource control policies (RCPs) into CloudFormation provides an efficient and scalable approach to managing and automating your AWS governance. After they’ve been imported, you can manage and update policies directly in CloudFormation, to help ensure consistency and version control across your organization. The tool also creates a Policies folder in your current directory, storing downloaded templates for use as a central repository and integration with a CI/CD pipeline.

By using CloudFormation Hooks, you can further improve your policy management by validating SCPs and RCPs against best practices and policy grammar. This approach centralizes your policy updates, making governance more automated and efficient while reducing the risk of misconfiguration.

Swara Gandhi

Swara Gandhi

Swara is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Enforce resource configuration to control access to new features with AWS

Post Syndicated from Yossi Cohen original https://aws.amazon.com/blogs/security/enforce-resource-configuration-to-control-access-to-new-features-with-aws/

Establishing and maintaining an effective security and governance posture has never been more important for enterprises. This post explains how you, as a security administrator, can use Amazon Web Services (AWS) to enforce resource configurations in a manner that is designed to be secure, scalable, and primarily focused on feature gating.

In this context, feature gating means that newly supported AWS features and configurations can’t be used unless you explicitly approve them. With feature gating, you maintain control over your AWS environment when new services and capabilities are introduced.

This blog post demonstrates a unique approach to giving users, such as DevOps teams, controlled flexibility within safe boundaries by allowing resource provisioning that uses only approved configurations. This approach also accommodates configurations that will be supported in future versions of the resource, keeping them restricted until explicitly approved, as shown in Figure 1.

Figure 1: Restrict resource provisioning to approved configurations only

Figure 1: Restrict resource provisioning to approved configurations only

Apply your resource configuration enforcement

As shown in Figure 2, our solution for resource configuration enforcement (RCFGE) uses AWS CloudFormation Hooks. By using Hooks, you can run custom logic during the provisioning of resources. These are proactive controls because you inspect and enforce resource configurations before the resource is created, updated, or deleted.

Your Hook will only be effective if CloudFormation supports the AWS resources that you are using and if you implement a service control policy (SCP) that helps prevent users from provisioning resources outside of CloudFormation.

Figure 2: How CloudFormation Hooks work

Figure 2: How CloudFormation Hooks work

The flow shown in Figure 2 consists of the following five steps:

  1. DevSecOps registers and configures a CloudFormation Hook in the account.
  2. DevOps specifies a CloudFormation template that defines the required resources and configurations.
  3. CloudFormation creates a new stack resource, starting the provisioning process based on the template.
  4. The Hook is triggered before provisioning for each resource that’s defined in the template, and runs custom validation logic.
  5. If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.

Make your solution scalable

To achieve scalable operations, you should implement a reusable and generic Hook that targets all supported CloudFormation resource types. This Hook enforces resource configuration by loading resource specification files from an external object storage, such as an Amazon Simple Storage Service (Amazon S3) bucket.

These specification files define validation rules in a declarative language. Using this approach, you can add and remove resource configuration validation rules by editing the declarative files. When you externalize custom logic as decoupled validation rules from the Hook, DevSecOps personnel can manage these rules at scale without affecting your infrastructure.

Figure 3: Externalize custom logic as validation rule files in an S3 bucket

Figure 3: Externalize custom logic as validation rule files in an S3 bucket

Figure 3 shows how the solution has been revised to support this approach. Steps 1–3 are the same as in the flow shown in Figure 2:

  1. DevSecOps registers and configures a CloudFormation Hook in the account.
  2. DevOps specifies a CloudFormation template that defines the required resources and configurations.
  3. CloudFormation creates a new stack resource, starting the provisioning process based on the template.
  4. The Hook is triggered before provisioning for each resource that’s defined in the template.
  5. The Hook loads the relevant resource specification file from the S3 bucket and executes the validation rules against the current resource in the CloudFormation template.
  6. If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.

You need to configure the Hook schema and the Hook configuration schema to evaluate the configurations of all supported resources across your AWS accounts before changes are provisioned. This setup should cover create, update, and delete operations so that the Hook can help prevent non-approved configurations across stacks.

By using AWS CloudFormation Guard, you can externalize validation rules from the Hook, as described in Extend your pre-commit hooks with AWS CloudFormation Guard. Guard is an open source, general purpose, policy-as-code (PaC) evaluation tool that validates CloudFormation templates against custom rules to help you stay aligned with your organizational policies. For example, the CT.S3.PR.1 rule specification demonstrates a Guard rule that requires an S3 bucket to have its settings configured to block public access. These validation rules apply to currently supported AWS resource configurations and features, but they don’t restrict potential future properties.

Boost your solution with feature gating

Your risk model might lead you to look for mechanisms that further restrict the AWS resource configurations that you allow in your environments. As you will see, the proposed solution restricts authorized workforce users so that they can use new configurations only if you enable them. The proposed approach uses feature gating because it continues to enforce your configurations even when AWS adds new options for your resources.

Guard aims to validate required constraints; but to meet the feature gating objective, you should implement validation rules that check whether resource configurations fulfill structural constraints described by the restricted version of CloudFormation resource schemas. These schemas help you confine the possible resource configurations that can be provisioned in your environment no matter what new configurations AWS introduces.

Figure 4: Enforce resource configuration with restricted resource schema templates

Figure 4: Enforce resource configuration with restricted resource schema templates

Figure 4 shows an updated version of the same flow where validation rules are implemented by using restricted resource schema templates, which are stored in an S3 bucket. These templates are based on the original CloudFormation resource schemas, representing a snapshot of these schemas at a specific point in time. Steps 1–4 are the same as in the flow shown in Figure 3:

  1. DevSecOps registers and configures a CloudFormation Hook in the account.
  2. DevOps specifies a CloudFormation template that defines the required resources and configurations.
  3. CloudFormation creates a new stack resource, starting the provisioning process based on the template.
  4. The Hook is triggered before provisioning for each resource that’s defined in the template.
  5. The Hook loads the relevant restricted resource schema template file from the S3 bucket and uses it to execute schema validation against the current resource in the CloudFormation template.
  6. If the validation checks pass, CloudFormation proceeds with provisioning; if not, the process is terminated.

A restricted resource schema template is a subset of its corresponding original CloudFormation resource schema. It includes additional constraints that limit certain properties to specific values and patterns or exclude certain properties entirely. Furthermore, these templates contain placeholders that you fill in with runtime values, such as the account ID, which your Hook provides as part of the Hook context.

Figure 5: Resource configuration enforcement (RCFGE) CloudFormation Hook flow

Figure 5: Resource configuration enforcement (RCFGE) CloudFormation Hook flow

As shown in Figure 5, the flow within the RCFGE CloudFormation Hook involves the following steps:

  1. The CloudFormation Hook is invoked with the Hook context and the resource’s configuration JSON object.
  2. The Hook loads the restricted resource schema template from the S3 bucket and substitutes placeholders with the Hook context runtime values, producing a valid JSON schema.
  3. The Hook validates the stack’s resource configuration JSON object against the schema. If it returns OperationStatus.SUCCESS, then CloudFormation proceeds with the provisioning process. If it returns OperationStatus.FAILED, then CloudFormation terminates the provisioning process.

If a restricted resource schema template for a CloudFormation resource type isn’t found in the S3 bucket, the schema validation step fails by default.

Sample excerpt of a restricted schema template for an S3 bucket resource

The following is an excerpt from a restricted schema template for an S3 bucket. At runtime, your Hook processes this template, substituting the placeholders with relevant values from the Hook context. In this example, the Hook replaces the <accountID> placeholder in the topic’s pattern with the actual account ID. The resulting JSON schema disallows additional properties beyond those defined by the schema and restricts the Amazon Simple Notification Service (Amazon SNS) topics that can be used for event notifications.

Note: In the code samples that follow, we’ve omitted some code for brevity—we’ve indicated these omissions with three periods: ...

{
  "type": "object",
  "required": [],
  "additionalProperties": false,
  "properties": {
        ...
      "NotificationConfiguration": {
          "$ref": "#/definitions/NotificationConfiguration"
      },
        ...
  },
  "definitions": {
        ...
      "NotificationConfiguration": {
          "type": "object",
          "additionalProperties": false,
          "properties": {
            ...
              "TopicConfigurations": {
                  "type": "array",
                  "uniqueItems": true,
                  "items": {
                      "$ref": "#/definitions/TopicConfiguration"
                  }
              }
          }
      },
        ...
      "TopicConfiguration": {
          "type": "object",
          "additionalProperties": false,
          "properties": {
        ...
              "Topic": {
                  "type": "string",
                  "pattern": "^arn:aws:sns::$<accountID>:.*$"
              },
        ...
            }
      },
  }
}

CloudFormation template for an S3 bucket that adheres to the restricted schema

Let’s assume that your account ID is 111122223333. The account ID is propagated to the Hook through the Hook context.

The following is an excerpt from a CloudFormation template that aligns with the restricted schema for an S3 bucket instantiated from the template shown previously. As a result, your Hook allows the corresponding CloudFormation stack to proceed.

{
   "AWSTemplateFormatVersion": "2010-09-09",
   "Resources": {
     "S3Bucket": {
       "Type": "AWS::S3::Bucket",
       "Properties": {
         "BucketName":
            "valid-bucket-sns-notification-configuration-template",
         "NotificationConfiguration": {
           "TopicConfigurations": [
             {
              "Topic":
                "arn:aws:sns:eu-west-1:111122223333:this-is-my-topic-and-I-trust-it",
              "Event": "s3:ObjectCreated:*"
             }
           ]
         }
       }
    }
  }
}

CloudFormation template for an S3 bucket that diverges from the restricted schema (example 1)

The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously because it attempts to configure the Amazon SNS topic for the notification configuration, which uses an Amazon Resource Name (ARN) of another account. As a result, your Hook causes the corresponding CloudFormation stack to fail.

{
   "AWSTemplateFormatVersion": "2010-09-09",
   "Resources": {
     "S3Bucket": {
       "Type": "AWS::S3::Bucket",
       "Properties": {
         "BucketName":
           "invalid-bucket-sns-notification-configuration-template",
         "NotificationConfiguration": {
            "TopicConfigurations": [
              {
               "Topic":
                 "arn:aws:sns:eu-west-1:444455556666:this-is-not-my-topic",
               "Event": "s3:ObjectCreated:*"
              }
            ]
         }
       }
     }
   }
}

CloudFormation template for an S3 bucket that diverges from the restricted schema (example 2)

The following is an excerpt from a CloudFormation template that doesn’t align with the restricted schema for an S3 bucket instantiated from the template shown previously. This time, it violates your feature gating objective by attempting to use a new, imaginary feature of an S3 bucket that isn’t approved for use by your restricted schema for an S3 bucket. As a result, your Hook causes the corresponding CloudFormation stack to fail.

{
  "AWSTemplateFormatVersion": "2010-09-09",
  "Resources": {
    "S3Bucket": {
      "Type": "AWS::S3::Bucket",
      "Properties": {
        "BucketName":
           "valid-bucket-sns-notification-configuration-template",
        "NewFeature": {
           "property-1": true,
           "property-2": "public"
        },                
        "NotificationConfiguration": {
          "TopicConfigurations": [
            {
              "Topic":
                 "arn:aws:sns:eu-west-1:111122223333:this-is-my-topic-and-I-trust-it",
              "Event": "s3:ObjectCreated:*"
            }
          ]
        }
      }
    }
  }
}

Protect your controls

If a security control itself isn’t protected adequately, it becomes a weak link in the security chain. For example, a surveillance camera (a physical security control) that isn’t securely mounted can be removed, rendering it useless. This principle also applies to your RCFGE solution.

Next, we will show you how to isolate management activities to a dedicated account and use SCPs as preventative controls.

Isolate RCFGE management in a dedicated account

Organizing your AWS environment by using multiple accounts is a best practice because it enhances security, simplifies management, and allows for better resource isolation and cost tracking. Isolating the operation and management of your RCFGE solution in its own dedicated account is essential for securing the solution’s resources.

With AWS CloudFormation StackSets, you can deploy and manage RCFGE stacks across multiple accounts and AWS Regions from a single central administrator account. This provides consistent and scalable infrastructure while maintaining centralized governance. With this functionality, you can deploy the RCFGE resources to existing accounts and automatically include new accounts as you add them to your organization, simplifying RCFGE management and providing uniformity across your environments. For more information, see Deploy CloudFormation Hooks to an Organization with service-managed StackSets.

Figure 6 shows how to extend that idea so that you can operate the RCFGE solution at scale while maintaining isolation and the separation of duties. The solution operates across three key account types:

  • Management account –use this account to create your organization and designate the CloudFormation StackSets delegated administrator account.
  • Delegated administrator account – this account serves as the centralized management point for the RCFGE solution. It contains a continuous integration and continuous delivery (CI/CD) pipeline that provisions RCFGE resources across the organization by using CloudFormation StackSets with service managed permissions. The account hosts a centralized S3 bucket that stores the RCFGE restricted resource schema templates. The security engineering team uses this account to submit Hook code and restricted resource schema template changes, which trigger the CI/CD pipeline.
  • Member accounts – each member account contains an RCFGE StackSet instance and an AWS Identity and Access Management (IAM) role for provisioning RCFGE resources. It also includes a CloudFormation Hook and an IAM role that allows the Hook to access the centralized S3 bucket with RCFGE restricted resource schema templates.

Figure 6: Securely operate the RCFGE solution

Figure 6: Securely operate the RCFGE solution

Let’s explore how the RCFGE solution architecture enforces resource configuration step by step, as shown in Figure 7.

Figure 7: CloudFormation stack deployment flow with RCFGE validation and enforcement

Figure 7: CloudFormation stack deployment flow with RCFGE validation and enforcement

  1. DevOps initiates the deployment by specifying a CloudFormation template that defines the resources and configurations needed.
  2. CloudFormation creates a new stack resource, initiating the resource provisioning process based on the provided template.
  3. The RCFGE CloudFormation Hook is triggered for each resource defined in the CloudFormation template.
  4. The Hook loads the corresponding restricted resource schema template from the S3 bucket.
  5. The Hook validates a resource configuration:
    • The Hook processes the restricted resource schema template to create a JSON schema.
    • It uses this JSON schema to validate the current resource in the CloudFormation template.
    • If the resource is invalid according to the schema, the provisioning process is terminated.
  6. If the current resource passes validation, CloudFormation proceeds with the resource provisioning process by creating and configuring the resources as specified in the template.

Use SCPs as preventive controls for your organization to help protect RCFGE

The following SCP excerpt accomplishes three objectives:

  • Implements a statement (see AllowedListActions) to explicitly specify the access that is allowed while other access is implicitly blocked.
  • Implements control objectives to help prevent changes to resources set up by the RCFGE solution (see ProtectRCFGEResources and ProtectStackSetExecutionRole).
  • Makes sure that AWS resource provisioning does not occur outside of CloudFormation (see ProvisionResourcesViaCloudFormationOnly).

In this SCP excerpt, the ProvisionResourcesViaCloudFormationOnly statement restricts CloudFormation stacks to being managed only through forward access sessions (FAS) in AWS IAM.

The ProvisionResourcesViaCloudFormationOnly statement explicitly prohibits direct create, update, and delete actions for all supported resources used in your environment. If needed, split this statement into multiple parts so you don’t exceed SCP size limits, while providing comprehensive coverage of your resources to make sure that they are provisioned and managed only through CloudFormation.

The ProtectStackSetExecutionRole statement in this example assumes that CloudFormation trusted access is activated with AWS Organizations, which is required by StackSets to deploy across accounts and Regions by using service managed permissions.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowedListActions",
      "Effect": "Allow",
      "Action": [
        "s3:CreateBucket",
        "s3:DeleteBucket",
        "s3:DeleteBucketPolicy",
        "s3:PutAnalyticsConfiguration",
        "s3:PutBucketLogging",
        "s3:PutBucketNotification",
        "s3:PutBucketObjectLockConfiguration",
        "s3:PutBucketPolicy",
        "s3:PutBucketTagging",
        "s3:PutBucketVersioning",
        "s3:PutLifecycleConfiguration",
        "s3:PutMetricsConfiguration",
        "s3:PutReplicationConfiguration",
        "s3:GetObject",
        ...
      ],
      "Resource": "*"
    },
    {
      "Sid": "ProtectRCFGEResources",
      "Effect": "Deny",
      "Action": "*",
      "Resource": [
        "arn:aws:cloudformation:*:*:stack/RCFGEStackSet",
        "arn:aws:cloudformation:*:*:*/hook/RCFGEHook/*",
        "arn:aws:iam::*:role/RCFGEHookExecutionRole"
      ],
      "Condition": {
        "ArnNotLike": {
          "aws:PrincipalArn": [
            "arn:aws:iam::*:role/stacksets-exec-*"
          ]
        }
      }
    },
    {
      "Sid": "ProtectStackSetExecutionRole",
      "Effect": "Deny",
      "Action": "*",
      "Resource": "arn:aws:iam::*:role/stacksets-exec-*"
    },
    {
      "Sid": "ProvisionResourcesViaCloudFormationOnly",
      "Effect": "Deny",
      "Action": [
        "s3:CreateBucket",
        "s3:DeleteBucket",
        "s3:DeleteBucketPolicy",
        "s3:PutAnalyticsConfiguration",
        "s3:PutBucketLogging",
        "s3:PutBucketNotification",
        "s3:PutBucketObjectLockConfiguration",
        "s3:PutBucketPolicy",
        "s3:PutBucketTagging",
        "s3:PutBucketVersioning",
        "s3:PutLifecycleConfiguration",
        "s3:PutMetricsConfiguration",
        "s3:PutReplicationConfiguration",
        ...
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:CalledViaFirst": "cloudformation.amazonaws.com"
        }
      }
    }
  ]
}

To allow the Hook to retrieve the necessary restricted resource schema templates, member accounts must be able to access the S3 bucket that contains the RCFGE templates. The following code sample shows the bucket policy for the S3 bucket that contains the RCFGE templates.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowRCFGEHookExecutionRoleGetRCFGETemplates",
      "Effect": "Allow",
      "Action": [
        "s3:GetObject"
      ],
      "Principal": "*",
      "Resource": "arn:aws:s3:::RCFGETemplates/*",
      "Condition": {
        "StringEquals": {
          "aws:PrincipalOrgID": "o-abcdef0123"
        },
        "ArnLike": {
          "aws:PrincipalArn": "arn:aws:iam::*:role/RCFGEHookExecutionRole"
        }
      }
    }
  ]
}

As shown in the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a policy that grants read-only access to the RCFGE templates that are stored in an S3 bucket in the RCFGE delegated administrator account, where 555555555555 represents the account ID.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowRCFGEHookExecutionRoleGetRCFGETemplates",
      "Effect": "Allow",
      "Action": [
        "s3:GetObject"
      ],
      "Resource": "arn:aws:s3:::RCFGETemplates/*",
      "Condition": {
        "StringEquals": {
          "aws:ResourceAccount": "555555555555"
        }
      }
    }
  ]
}

In the following code sample, the RCFGEHookExecutionRole IAM role in member accounts has a trust policy that allows it to be assumed only by the relevant CloudFormation service principals, where 444455556666 represents the account ID of the member account.

{
  "Version": "2012-10-17",
  "Statement": {
    "Sid": "AllowRCFGEHookExecutionRoleGetRCFGETemplatesTrust",
    "Effect": "Allow",
    "Principal": {
      "Service": [
        "hooks.cloudformation.amazonaws.com",
        "resources.cloudformation.amazonaws.com"
      ]
    },
    "Action": "sts:AssumeRole",
    "Condition": {
      "ArnLike": {
        "aws:SourceArn": "arn:aws:cloudformation:eu-west-1:444455556666:type/hook/RCFGEHook/*"
      }
    }
  }
}

Define baseline configuration for RCFGE and continuous monitoring with AWS Config

Defense in depth is an effective strategy because if one line of defense fails, additional layers are in place to help stop threats at subsequent points. With AWS Config, you can capture the configuration of RCFGE resources over time. You can set up AWS Config custom rules to automatically assess the compliance of your RCFGE resources against predefined policies. For example, you can use an AWS Config custom rule to make sure that the RCFGE Hook hasn’t been altered or removed.

Conclusion

In this post, you learned how to use CloudFormation Hooks to create a resource configuration enforcement (RCFGE) solution on AWS that is designed to be secure and scalable and that supports feature gating. Using this approach, you, as a security administrator, can maintain strict control over resource configurations and feature adoption across your AWS environments. The solution provides a balanced approach to governance, so that DevOps teams have the flexibility to work within approved boundaries while making sure that new AWS features are only accessible after explicit approval.

If you have feedback about this post, submit comments in the Comments section. For questions, start a new thread on the CloudFormation re:Post or contact AWS Support.
 

Yossi Cohen
Yossi Cohen

Yossi is a Senior Security Specialist Solutions Architect at AWS for the public sector in the EMEA region. Yossi has over two decades of experience in cloud-native architecture development, design, operations, technical due diligence, and governance in highly regulated environments. At AWS, Yossi collaborates closely with defense, intelligence, government, and public sector clients, helping them navigate their unique threat landscapes.
Yaniv Rozenboim
Yaniv Rozenboim

Yaniv is a Senior Solutions Architect at AWS with extensive experience in cloud architecture and security. He specializes in designing and implementing secure, scalable, and efficient cloud infrastructures. Yaniv works closely with clients to help them achieve their business goals through AWS technologies.

Simplify governance with declarative policies

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/simplify-governance-with-declarative-policies/

Today, I am happy to announce declarative policies, a new capability that helps you declare and enforce desired configuration for a given AWS Service at scale across your organization.

It is common for customers to create standards within their organizations for how cloud resources should be configured. For example, they might require blocking public access for Amazon EBS snapshots. They want these standards to be defined once centrally and enforced across all their accounts, including those that join the organization in the future. Additionally, whenever a cloud operator attempts to configure a resource in a way that does not meet the standard, they want that operator to receive a useful, actionable error message that explains how to remediate the configuration.

Declarative policies address these challenges by helping you to define and enforce desired configuration for AWS services with a few clicks or commands. You can select the configuration you want such as “block public access for VPCs” and AWS will automatically ensure that the desired state is enforced across your multi-account environment (or parts of it) once you attach the policy. This approach reduces the complexity of achieving the desired configuration. Once the configuration is set, it is maintained, even as new features or new APIs are added. Additionally, with declarative policies, administrators have visibility into the current state of service attributes across their environment, and – unlike access control policies, which cannot leak information to those without permissions – end users see custom error messages configured by their organization’s administrators, redirecting them to internal resources or support channels.

“ABSA Group operates in a heavily regulated environment and as we adopt more services, we use SCP policy exclusions to restrict actions and Config rules to detect violations. However, we must create an exception for every new API or feature. With declarative policies, we can simply set VPC Block Public Access to true and have peace of mind that no users, service-linked roles, or future APIs can facilitate public access in our AWS Organizations.” explains Vojtech Mencl, Lead Product Engineer at ABSA, a multinational banking and financial services conglomerate based in Johannesburg, South Africa.

“With custom error messages, we can easily redirect end users to an internal portal for more information on why their action failed. This drastically reduces the operational complexity for governance and accelerates our migration to AWS.” says Matt Draper, Principal Engineer at ABSA.

At this launch, declarative policies supports Amazon Elastic Compute Cloud (Amazon EC2), Amazon Virtual Private Cloud (Amazon VPC), and Amazon Elastic Block Store (Amazon EBS) services. Available service attributes include enforcing IMDSv2, allowing troubleshooting though serial console, allowed Amazon Machine Image (AMI) settings, and blocking public access for Amazon EBS snapshots, Amazon EC2 AMI, and VPC. When new accounts are added to an organization, they will inherit the declarative policy applied at the organization, organizational unit (OU) or account level.

You can create declarative policies through the AWS Organizations console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, or through AWS Control Tower. Policies can be applied at the organization, OU, or account level. When attached, declarative policies prevent non-compliant actions regardless of whether they were invoked using an AWS Identity and Access Management (IAM) role you created or by an AWS service using a service-linked role.

Getting started with declarative policies
To demonstrate declarative policies, I will walk you through an example. Let’s say that as the security administrator for a large enterprise with hundreds of AWS accounts, I’m responsible for maintaining our organization’s strict security posture. At our company, we have several critical security requirements: we maintain tight control over internet access across all our networks, we only allow AMIs from specific trusted providers, and we need to ensure that no VPC resources are accidentally exposed to the public internet. With declarative policies, I can implement these requirements efficiently. Let me show you how I set this up in my environment.

I go to the AWS Organizations console and choose Policies in the navigation pane. I choose Declarative policies for EC2 under the Supported policy types.

I choose Enable declarative policies for EC2 to enable the feature.

After declarative policies is enabled, I can define and enforce desired configurations for EC2 across all of the accounts in my AWS Organizations.

Before I create declarative policies, as the organization’s administrator, I want to understand the current status of my AWS environment using the account status report, which is a feature of declarative policies. The report offers both a summary view and a detailed CSV file, covering all accounts and AWS Regions within a selected organizational scope. It helps me assess readiness before attaching a policy.

On the next page, I choose Generate status report. I choose an Amazon Simple Storage Service (Amazon S3) bucket under Report S3 URI and choose accounts and OUs to include in the report scope.

Note that the S3 bucket requires the following policy attached to it in order to store the status report:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "DeclarativePoliciesReportBucket",
            "Effect": "Allow",
            "Principal": {
                "Service": [
                    "report.declarative-policies-ec2.amazonaws.com"
                ]
            },
            "Action": [
                "s3:PutObject"
            ],
            "Resource": "arn:aws:s3:::<bucketName>/*",
            "Condition": {
                "StringEquals": {
                    "aws:SourceArn": "arn:<partition>:declarative-policies-ec2:<region>:<accountId>:*"
                }
            }
        }
    ]
}

I choose Submit.

When complete, the report is stored in the Amazon S3 bucket I specified. On the View account status report page, I can choose between multiple reports from Reports dropdown to observe what is the current status of various attributes.

I check the Amazon S3 bucket I provided to store a CSV file, which provides the detailed readiness report. I observe what my current state is across my organization unit across different regions.

After I assess the account status, I continue to create a policy. I choose Create policy on the Declarative policies for EC2 page.

On the next page, I enter a Policy name and optionally a Policy description.

In this demo, I use Visual Editor to show how to add service attributes. These attributes include Serial Console Access, Instance Metadata Defaults, Image Block Public Access, Snapshot Block Public Access, VPC Block Public Access, and Allowed Image Settings. I can use JSON Editor to add them manually or to observe the policies I added using Visual Editor. First, I choose VPC Block Public Access to control internet access for resources in my VPC from internet gateways. I choose Block ingress under Internet gateway state. When enabled, this immediately prevents public access without mutating resources and can be rolled back.

As a second attribute, I choose Allowed Image Settings to control the allowed images criteria for AMIs. This is useful because I can ensure all instance launches use a golden AMI that an account or set of accounts generates in my organization, or one provided by a vendor like Amazon or Ubuntu. I choose Enabled under Allowed Image Settings. I choose amazon under Provider. Declarative policies provides transparency with customizable error messages to help reduce end-user frustration. You can optionally add a Custom error message to be displayed when organization members are unable to perform a restricted action. To complete the process of generating the policy, I choose Create policy.

Now, I need to attach the policy to my organization or specific OUs. I choose Attach policy under Actions.

I choose my organization or specific OUs and choose Attach policy.

When an account joins an organization or an OU, the declarative policy attached to it takes immediate effect and all subsequent non-compliant actions will fail (except for VPC Block Public Access, which will immediately curtail public access). Existing resources in the account will not be deleted.

Now available
Declarative policies streamlines governance for AWS customers by reducing policy maintenance overhead, providing consistent enforcement across accounts, and offering transparency to administrators and end users.

Declarative policies are now available in AWS commercial, China and AWS GovCloud (US) Regions.

To learn more about declarative policies and start enforcing them in your organization, visit the declarative policies documentation.

— Esra