Tag Archives: Oauth

From all-or-nothing to task-based OAuth consent

Post Syndicated from Miller Vargas original https://blog.cloudflare.com/task-based-oauth-consent/

Since June, developers have created thousands of third-party OAuth apps on Cloudflare, with more than a million authorizations since.  

OAuth makes delegated access possible. It lets applications act on a user’s behalf without asking them to handle long-lived credentials or hand over a password. That model works well when an application can describe its access needs with a small set of scopes. 

Developers use OAuth for SaaS integrations, internal tools, CLIs, and agents. Our permission model has become more granular over time to support better scoping of these different workflows. That is great for security, but it makes a purely all-or-nothing consent screen hard to justify.

Cloudflare OAuth already allows clients to request a subset of their configured scopes. But once the client made that request, the user could not narrow it any further on the consent screen. For the user on the consent screen, the experience was still an all-or-nothing one. If an application requested more access than a user was comfortable granting, their only options were to approve the full request, or deny outright. 

MCP servers are a good example of this. An MCP server might request a broad set of permissions, because in theory an agent could use all of them. But most users would not want an agent to have that much access. Before this feature, the only way to handle this was for the app developer to build a custom scope selection screen before sending the user to our consent flow.

Today, we’re introducing OAuth scope customization. Client owners can mark specific scopes as optional when configuring an OAuth client, giving users the ability to grant a narrower subset of an application’s requested access at authorization time.

The OAuth spec already allows authorization servers to grant a narrower set of scopes than what was requested. We built on top of that flexibility to make this work cleanly for every existing app.

More control, without overwhelming users

Our goal with introducing scope selection is to give security conscious users more flexibility to make the right choices for their use case, without turning the consent screen into a long scope checklist. 

With scope customization: 

  • Developers can mark specific scopes on an OAuth client as required or optional
  • At authorization time, users can deselect optional scopes from the requested set
  • Required and optional scopes are evaluated against the scopes requested for that authorization flow
  • If no optional scopes are requested, the consent experience stays the same
  • By default, the consent screen still grants the full requested scope set.  

Scoping to the authorization request

One important detail is that required and optional scopes are evaluated only against the scopes requested in a specific authorization flow, not every scope configured on the client. That matters because OAuth clients do not always request their full configured scope set.

For example, a client might be configured with user-details.read, workers-scripts.write, workers-kv-storage.write, and zone.read, while marking workers-kv-storage.write and zone.read as optional. If that client starts an authorization flow requesting all four scopes, the consent screen will evaluate all four. In that case, user-details.read and workers-scripts.write remain required, while the user can choose whether to grant workers-kv-storage.write and zone.read.

But if the client later requests only workers-scripts.write and zone.read, then only those two scopes are considered for that authorization flow. user-details.read and workers-kv-storage.write would not be shown or enforced, because they were not requested.

This keeps the consent screen focused on the task at hand, rather than every capability the application could request. It also means existing OAuth clients keep their current behavior by default: if a client does not opt into optional scopes, the consent flow remains unchanged.

Configuring an OAuth client to use optional scopes

Developers can opt into scope customization when configuring an OAuth client. Scopes continue to be configured as they are today, and clients can now additionally specify which of those scopes are optional: 

In the example above, the client can request all four scopes, but the user may only opt out of the workers-kv-storage.write and zone.read scopes during consent. user-details:read and workers-scripts.write remain required if they are included in the authorization request. 

If the client later requests only workers-scripts.write and zone.read, then only those two scopes are considered for that authorization flow. user-details.read and workers-kv-storage.write would not be shown or enforced because it was not requested.

Building with partial grants in mind

When a user deselects any optional scopes and completes the authorization flow, the generated access token will only contain the scopes they consented to. For developers, this means you need to check the granted scope set after exchanging the authorization code, rather than assuming the full requested set of scopes was approved.

An app that handles a narrower grant gracefully, for example an agent that operates within whatever subset of permissions it receives, is one that users feel comfortable authorizing. Requesting only the permissions needed and marking the rest as optional is a good sign to users that your app respects their access decisions.

Scopes for every Product

Over the next few weeks, we will be expanding our account & zone-level role surface to cover nearly every Cloudflare product. That means more API token roles, account membership options, and OAuth scopes, giving customers the tools to secure workloads with the right level of access. 

Build with Optional Scopes

Allowing developers and users to better restrict access through optional OAuth scopes is an important step toward a more flexible and trustworthy consent experience on Cloudflare. With optional scopes, developers can build more nuanced authorization flows, and users gain more control over what they approve. 

To get started with Third Party OAuth, take a look at our documentation or jump straight to the OAuth apps page in the dashboard and create your first OAuth app

Thank you to our amazing interns

This feature is one of the many that we built with the help of our 1,111 interns. Congratulations to Miller Vargas and José Enrique Rodriguez on your high impact contributions here. Miller is a senior at the University of Texas – Austin studying computer science and math; and José is a senior at Universidad Panamericana studying engineering, data intelligence, and cybersecurity.

Introducing OAuth Support for AWS MCP Server

Post Syndicated from Vaibhav Chowla original https://aws.amazon.com/blogs/security/introducing-oauth-support-for-aws-mcp-server/

AWS MCP Server using the same credentials and sign-in methods that you already use for connecting to the AWS Management Console or AWS Command Line Interface (AWS CLI) through a familiar browser-based experience powered by industry-standard OAuth. This new sign-in path supports AWS Identity and Access Management (IAM) federation, AWS IAM Identity Center, and root or IAM users.

In addition, AWS is introducing several new security and governance tools, including: new global condition keys for OAuth, token introspection and revocation, dynamic client registration, new AWS CloudTrail elements, and a new API for headless OAuth connectivity. All of this is compatible with your existing IAM configuration including permissions, roles, and federated access.

In this post, you’ll learn how to connect your agents to the AWS MCP Server, understand how AWS Sign-In authorizes agent access, and manage access using new security and governance capabilities.

How to connect an agent to the AWS MCP Server

This walkthrough uses Claude Code, but the same steps apply to any agent that supports Model Context Protocol (MCP) such as Kiro, Codex, and Gemini. See Setting up the AWS MCP Server for how to connect the AWS MCP Server to an agent.

Prerequisite permissions

To connect an agent to the AWS MCP Server, you’ll need the IAM permissions required for OAuth-based sign-in. The following AWS CLI command adds a managed policy with required permissions to your IAM role (remember to replace <MyRole> with your IAM role):

aws iam attach-role-policy \
  --role-name <MyRole> \
  --policy-arn arn:aws:iam::aws:policy/AWSMCPSignInOAuthAccessPolicy

Step 1: Configure the AWS MCP Server on your agent

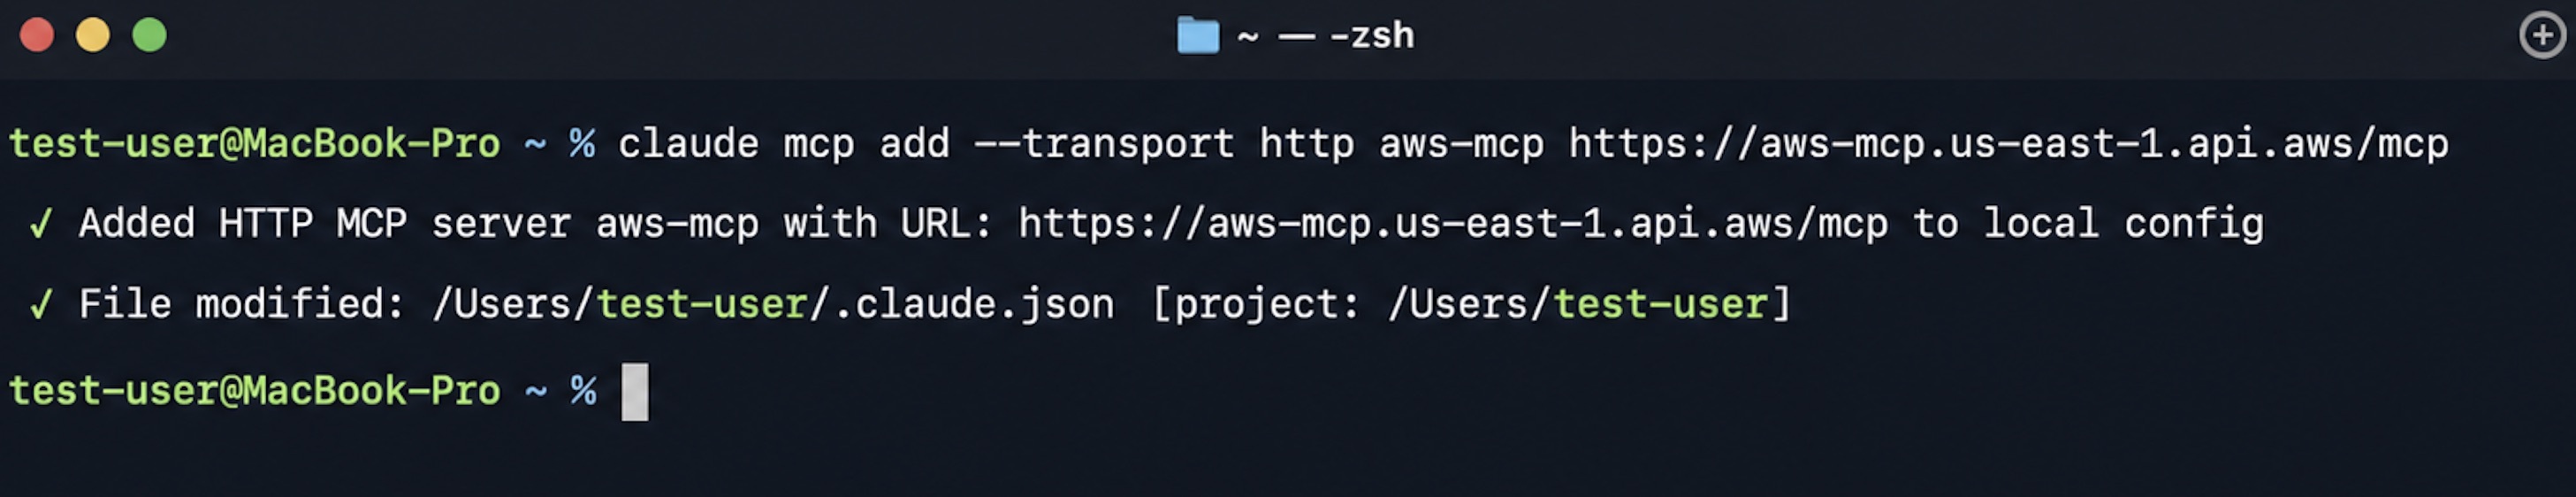
Run the following command to add the AWS MCP Server endpoint to your agent’s configuration as shown in Figure 1:

claude mcp add --transport http aws-mcp https://aws-mcp.us-east-1.api.aws/mcp

Figure 1: Adding the AWS MCP Server endpoint to Claude Code

Figure 1: Adding the AWS MCP Server endpoint to Claude Code

Step 2: Review the authorization request

The first time your agent needs to access the AWS MCP Server, it opens a browser and redirects you to an AWS Sign-In page, shown in Figure 2. Authenticate as you would on AWS console or AWS CLI, review the authorization request, and approve access. You should receive an Authorization successful message.

Figure 2: Review authorization request

Figure 2: Review authorization request

Note that if you already have an active AWS Sign-In session (e.g., because you previously signed in to the console earlier in the day), you can reuse that session without needing to sign in again.

Step 3: Start using AWS tools

After connecting your agent to the AWS MCP Server, you can begin invoking tools provided by the server. To verify that Claude Code is connected to the AWS MCP Server, start Claude Code and run the following command:

/mcp

The command displays the configured MCP servers and confirms that the AWS MCP Server is connected and ready to use with your AWS credentials.

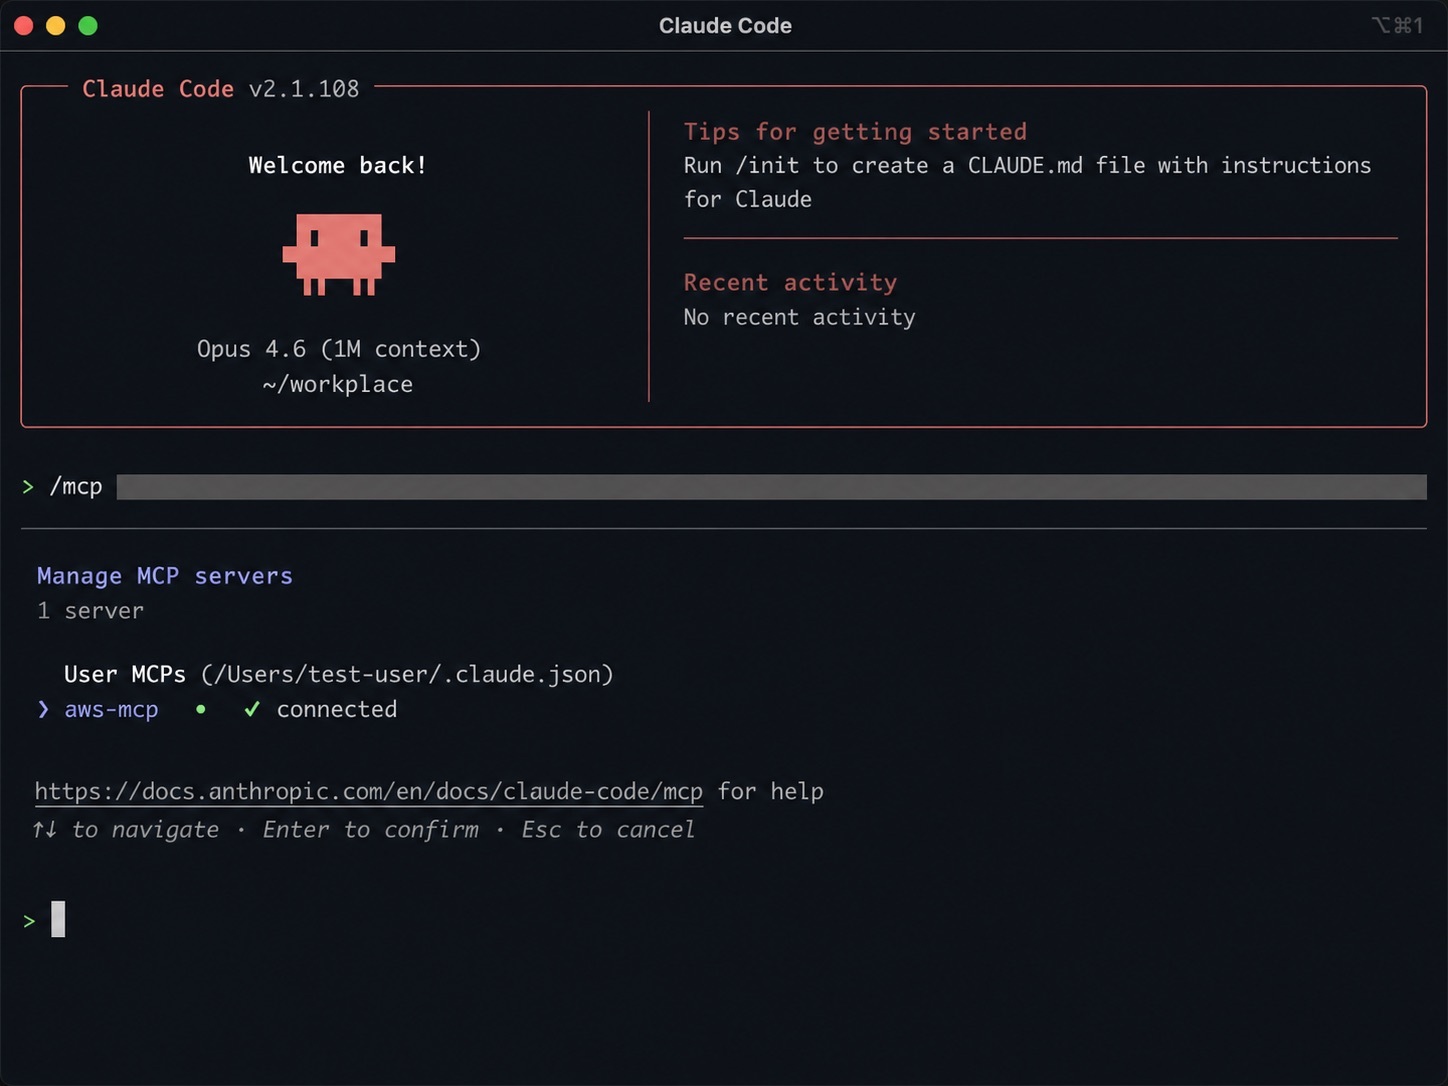
Figure 3 shows an example of a successful connection to the AWS MCP Server.

Figure 3: Verifying the AWS MCP Server connection in Claude Code

Figure 3: Verifying the AWS MCP Server connection in Claude Code

After the connection is established, you can ask Claude Code to invoke tools provided by the AWS MCP Server. For example, enter the following prompt:

Deploy a sample serverless web application into my development AWS account

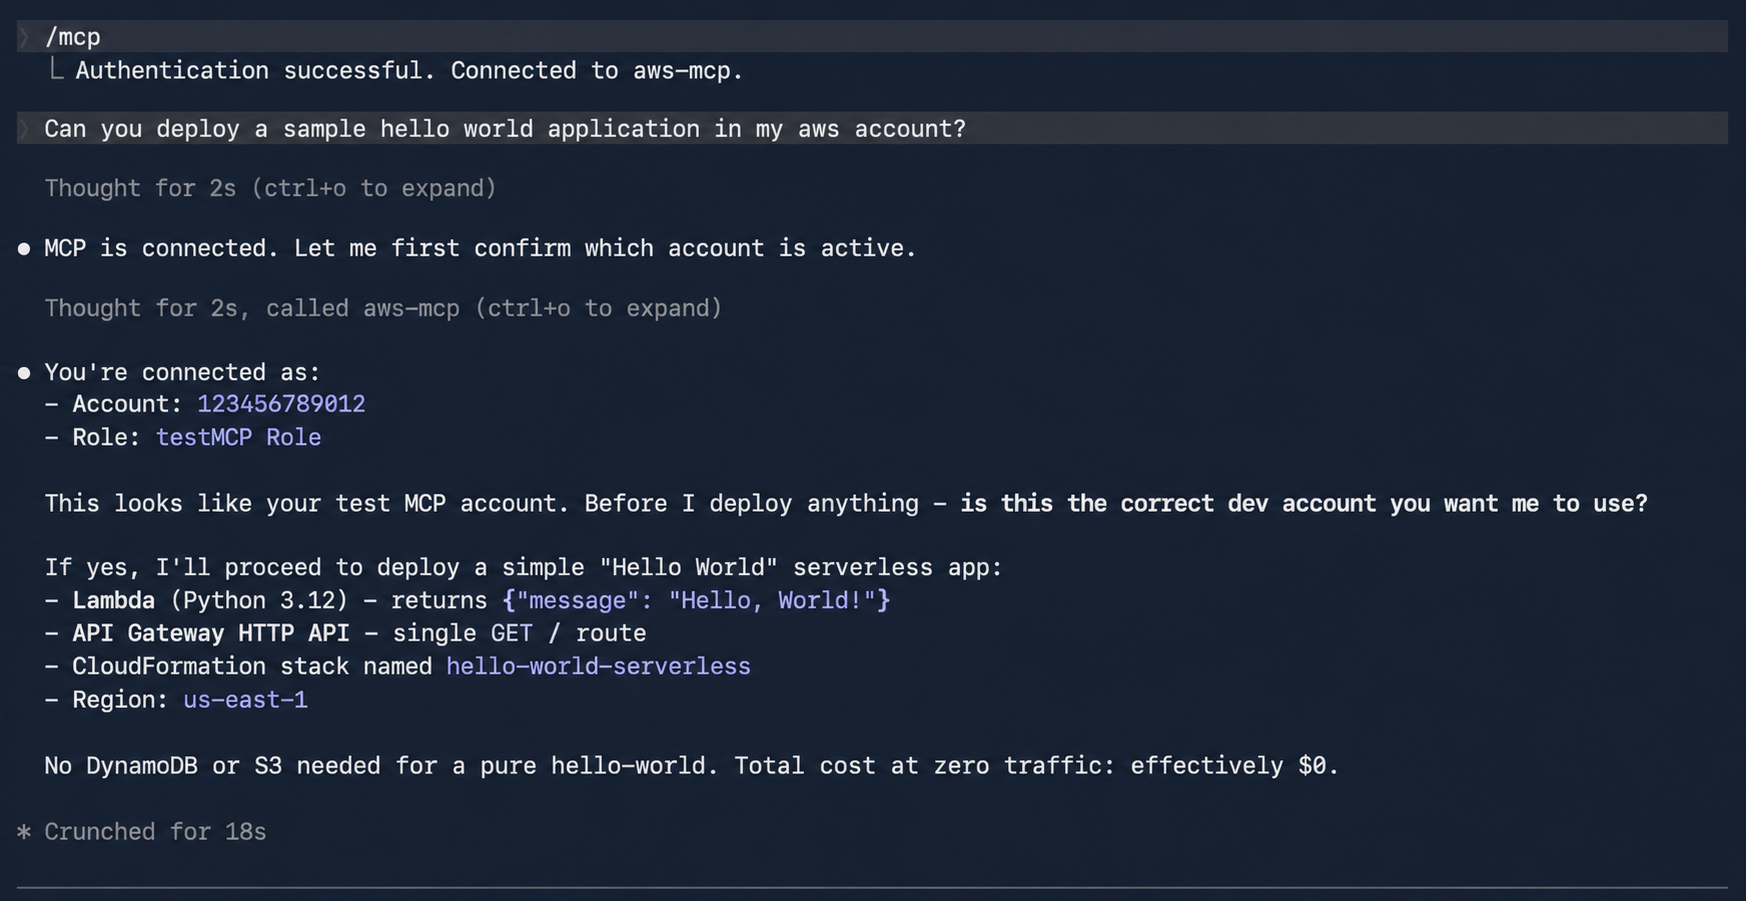
Claude Code uses the AWS MCP Server to identify the active AWS account, confirm the target account, and describe the deployment it plans to perform before invoking AWS services on your behalf.

Figure 4 shows Claude Code confirming the active AWS account and outlining the resources that will be deployed.

Figure 4: Using Claude Code to deploy a sample serverless application through the AWS MCP Server

Figure 4: Using Claude Code to deploy a sample serverless application through the AWS MCP Server

Authorization models and how they work

AWS Sign-In supports two authorization models for connecting agents to the AWS MCP Server:

  • Interactive authorization for developer’s AI agents using browser based authentication
  • Non-interactive (headless) authorization for applications and AI agents that already have AWS credentials and don’t have access to a browser

Note that authorizing an agent allows it to access the AWS MCP Server on your behalf. It doesn’t grant the agent additional AWS permissions. Every request is still evaluated using your existing IAM policies, SCPs, RCPs, permission boundaries, and other organizational controls.

Interactive access

In the interactive case, the agent first discovers the AWS Sign-In OAuth server and then registers itself as an OAuth client using Dynamic Client Registration (DCR). It then redirects you to an AWS Sign-In page where you authenticate and authorize access (step 2 in the preceding section). After successful authorization, AWS Sign-In then issues short-lived access tokens and refresh tokens that authorize the agent to access the AWS MCP Server on your behalf. AWS Sign-In automatically manages token issuance and token refresh, enabling authorized agents to continue accessing the AWS MCP Server without requiring you to repeatedly sign in.

The interactive authorization model supports three distinct sign-in methods: native AWS IAM credentials for individual developers, managed access through AWS IAM Identity Center for enterprises, and seamless federated access via third-party providers like Okta and Ping Identity for larger organizations

OAuth server metadata and DCR

Before an agent can request authorization, it must discover the AWS Sign-In OAuth endpoints and register itself as an OAuth client. AWS Sign-In supports OAuth metadata discovery and DCR, allowing supported agents to configure themselves automatically without requiring developers to manually provision OAuth client IDs and client secretsWhen an agent connects to the AWS MCP Server for the first time, it retrieves the AWS MCP Server’s protected resource metadata (RFC 9728) and the AWS Sign-In OAuth metadata (RFC 8414). The agent then uses RFC 7591)) to register with AWS Sign-In, obtain a client ID, and initiate the standard OAuth authorization code flow.

AWS Sign-In supports OAuth discovery and DCR for agents running on local workstations and supported hosted environments. For the current list of supported agents and environments, see Supported redirect URIs for the AWS MCP Server.

Non-interactive access to the AWS MCP Server

Non-interactive (headless) authorization is for agents and applications that run without a browser or human in the loop, and thus don’t require interactive sign-in. This allows agents that already have AWS credentials to obtain OAuth access tokens and connect to the AWS MCP Server. The following is an example of how to obtain an access token.

aws signin create-oauth2-token-with-iam \ 
--grant-type client_credentials \ 
--resource aws-mcp.amazonaws.com \  
--region us-east-1 
{ 
"accessToken": "ASOA****************************************...", 
"tokenType": "Bearer", 
"expiresIn": 3600 
}

In the non-interactive case, AWS Sign-In implements the OAuth client credentials grant using AWS security credentials instead of a static client secret. Applications authenticate to the AWS Sign-In token endpoint using SigV4 creds, and AWS Sign-In returns a short-lived OAuth access token that can be used to access the AWS MCP Server.

Please note you may have to update the SDK and AWS CLI, please refer to CLI guide.

Managing OAuth access

AWS Sign-In extends the existing IAM authorization model with capabilities for governing OAuth access to the AWS MCP Server. Administrators can use familiar IAM policies together with new OAuth-specific controls.

Granting OAuth permissions

OAuth access is governed using IAM policies and requires the following IAM actions:

  • signin:AuthorizeOAuth2Access – Allows users to sign in interactively using the OAuth authorization code flow
  • signin:CreateOAuth2Token – Allows applications to obtain OAuth access tokens by exchanging authorization codes, refresh tokens, or using client credentials

When an application requests access, AWS Sign-In creates an OAuth authorization grant between the agent and the AWS MCP Server. This grant is represented as an IAM resource, which the preceding AWS Sign-In actions are authorized against.

arn:aws:signin:us-east-1:012345678910:service-principal/aws-mcp.amazonaws.com

OAuth authorization grants are represented as IAM resource enabling administrators to use standard IAM policy constructs, including global condition keys, together with OAuth-specific condition keys to control how authorization grants are created and used.

Governing OAuth access

AWS Sign-In introduces OAuth-specific condition keys that allow administrators to govern how agents obtain OAuth authorization. The following examples demonstrate common governance patterns.

To restrict OAuth authorization to localhost:

In addition to accessing the AWS MCP Server with agents on your local workstation, AWS supports signing into the AWS MCP Server on select hosted providers through dynamic client registration. Click here to view the list of supported remote providers. Many organizations want to allow developers to authorize agents running on their local workstations while preventing OAuth tokens from being delivered to untrusted redirect URIs or using unsupported authorization flows. The following policy allows only the OAuth authorization code and refresh token flows for the AWS MCP server and restricts token delivery tolocalhost.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "signin:AuthorizeOAuth2Access",
        "signin:CreateOAuth2Token"
      ],
      "Resource": "arn:aws:signin:*:*:service-principal/aws-mcp.amazonaws.com",
      "Condition": {
        "StringLike": {
          "signin:OAuthRedirectUri": "http://localhost:*"
        },
        "StringEquals": {
          "signin:OAuthGrantType": [
            "authorization_code",
            "refresh_token"
          ]
        }
      }
    }
  ]
}

To deny access for a specific OAuth session

Use the aws:SignInSessionArn global condition key to deny authorization associated with a specific sign-in session. This allows administrators to contain a suspicious or compromised authorization session without affecting other active sessions.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Action": [
        "*"
      ],
      "Resource": "*",
      "Condition": {
        "ArnEquals": {
          "aws:SignInSessionArn": "arn:aws:signin:us-east-1:111122223333:session/abc123-example-session-id"
        }
      }
    }
  ]
}

These examples demonstrate common governance patterns. Additional IAM and SCP examples are available in the AWS Sign-In condition keys reference.

Revoking OAuth tokens

AWS Sign-In provides OAuth token introspection and token revocation APIs that allow administrators to build custom tools for token validation and revocation. Access to these APIs is controlled through the signin:IntrospectOAuth2Token and signin:RevokeOAuth2Token permissions. IAM principals with permissions are allowed to introspect and revoke tokens for the same account.

The introspection API can be used to determine whether a token is active and obtain information about the associated authorization. The revocation API allows administrators and security tools to revoke individual refresh tokens without affecting other active sessions. For example, if an organization needs to invalidate access for a specific OAuth authorization, account admins can revoke the associated refresh token without affecting other active sessions.

Monitoring OAuth activity

OAuth-related activities are recorded in AWS CloudTrail, including authorization requests, token issuance, token revocation, and token introspection events. CloudTrail logs also capture details such as the OAuth client, target the AWS MCP Server, redirect URI, authorization flow, and associated sign-in session. In addition, AWS API calls made using OAuth access tokens include the associated aws:SignInSessionArn context, allowing organizations to correlate API activity with the originating OAuth sign-in session.

This allows security teams to monitor OAuth usage, investigate authorization activity, detect anomalous behavior, and integrate OAuth events into existing auditing, compliance, and incident response workflows alongside other AWS activity.

Here’s a CloudTrail sample for an AuthorizeOAuth2Access event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP****:testuser",
        "arn": "arn:aws:sts::111111111111:assumed-role/Admin/testuser",
        "accountId": "111111111111",
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROA2IRT4N5U4RDHM2LG4",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": "111111111111",
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2026-06-09T05:06:39Z",
                "mfaAuthenticated": "false"
            }
        }
    },
    "eventTime": "2026-06-09T05:09:00Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "AuthorizeOAuth2Access",
    "awsRegion": "us-west-2",
    "sourceIPAddress": "192.0.0.2",
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/149.0.0.0 Safari/537.36",
    "requestParameters": {
        "resource": "https://aws-mcp.us-west-2.api.aws/mcp",
        "redirect_uri": "http://127.0.0.1:60432/oauth/callback",
        "code_challenge_method": "S256",
        "client_id": "arn:aws:signin:us-west-2::external-client/dcr/609544da-aasa-49a4-ab11-c2r457fa999"
    },
    "responseElements": null,
    "additionalEventData": {
        "success": "true"
    },
    "requestID": "4fb4ff7b-6yu7-9090-78i9-9c0088a65134",
    "eventID": "bb05b222-31ec-4237-b8e7-8eb26d4fd48b",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "111111111111",
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-west-2.oauth.signin.aws"
    }
}

Here’s a CloudTrail sample for a CreateOAuth2Token event:

{
    "eventVersion": "1.11",
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROATJHQDX737YZP7****:testuser",
        "arn": "arn:aws:sts::111111111111:assumed-role/Admin/testuser",
        "accountId": "111111111111",
        "sessionContext": {
            "sessionIssuer": {
                "type": "Role",
                "principalId": "AROA2IRT4N5U4RDHM****",
                "arn": "arn:aws:iam::111111111111:role/Admin",
                "accountId": "111111111111",
                "userName": "Admin"
            },
            "attributes": {
                "creationDate": "2026-06-09T05:06:39Z",
                "mfaAuthenticated": "false"
            },
            "signInSessionArn":""
            
        }
    },
    "eventTime": "2026-06-09T05:10:04Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "CreateOAuth2Token",
    "awsRegion": "us-west-2",
    "sourceIPAddress": "192.0.0.2",
    "userAgent": "curl/8.7.1",
    "requestParameters": {
        "resource": "https://aws-mcp.us-west-2.api.aws/mcp",
        "client_id": "arn:aws:signin:us-west-2::external-client/dcr/609544da-b3dd-49a4-ab11-c2e98d7fa999"
    },
    "responseElements": null,
    "additionalEventData": {
        "signInSessionArn": "arn:aws:signin:us-west-2:111111111111:session/daff060f-7871-5tg6-67yu-a07bbdabe61a",
        "grant_type": "refresh_token",
        "success": "true"
    },
    "requestID": "44d6d7ce-e4r5-4cbf-0909-bfb8a8295a76",
    "eventID": "f79cc63f-b383-4e3c-a1e5-97c7db1ab833",
    "readOnly": true,
    "eventType": "AwsApiCall",
    "managementEvent": true,
    "recipientAccountId": "111111111111",
    "eventCategory": "Management",
    "tlsDetails": {
        "tlsVersion": "TLSv1.3",
        "cipherSuite": "TLS_AES_128_GCM_SHA256",
        "clientProvidedHostHeader": "us-west-2.oauth.signin.aws"
    }
}

Additional audit events and logging details for calls made using OAuth access tokens to the AWS MCP Server can be found in Logging AWS MCP Server API calls using AWS CloudTrail.

Conclusion

AWS Sign-In support for OAuth enables you to securely connect to the AWS MCP Server using industry-standard authorization. This release simplifies application and agent integration with AWS while supporting your existing IAM setup, governance, and auditing capabilities.

To learn more, see Sign-In with OAuth 2.0 in the AWS Sign-In User Guide and Setting up the AWS MCP Server in the Agent Toolkit for AWS User Guide.

If you have feedback about this post, submit comments in the Comments section below.


Vaibhav Chowla

Vaibhav Chowla

Vaibhav is a Senior Technical Product Manager at AWS, specializing in AWS Identity products. He focuses on enhancing user authentication and security, helping customers of all sizes solve complex identity and access management (IAM) challenges. Outside of technology, Vaibhav enjoys traveling and exploring new cultures and cuisines.

Jaimin Bhatt

Jaimin Bhatt

Jaimin is a Principal Software Engineer at AWS. He works on AWS Identity and Access Management (IAM) across sign-in, threat detection, and the authentication and authorization that secures access to AWS. Jaimin is an active participant in multiple industry standards bodies. Previously, he led work on data perimeter controls for AWS Management Console sign-in, multi-session support for the console, a simplified AWS CLI sign-in experience, and the internal Amazon identity provider.

Ankur Joshi

Ankur Joshi

Ankur is a Software Development Manager on the AWS Identity Sign-In team. His team focuses on delivering secure and resilient authentication mechanisms and access controls for AWS customers.

Enforce least-privilege authorization in multi-agent AI chains using Cedar

Post Syndicated from Dhananjay Karanjkar original https://aws.amazon.com/blogs/security/enforce-least-privilege-authorization-in-multi-agent-ai-chains-using-cedar/

If you’re building multi-agent AI systems, you need to prevent authorization scope from silently expanding as agents delegate tasks through multi-hop chains. Without proper controls, an agent can potentially act beyond what the originating user authorized, even when role-based access control (RBAC) policies are in place. The OWASP Top 10 for Agentic Applications classifies this risk as ASI03: Identity & Privilege Abuse.

This post shows you how to address the potential risk using a three-layer policy model built with Cedar, an open source authorization policy language, deployed on Amazon Web Services (AWS). The reference implementation uses OAuth 2.0 for authentication and Cedar for authorization. A trusted identity provider authenticates the originating user, then Cedar policies enforce authorization across three layers using verified token claims.

Reference implementation overview

To enforce authorization at each hop in a multi-agent delegation chain, the reference implementation uses two AWS Lambda functions in sequence. A Model Context Protocol (MCP) adapter Lambda function normalizes inbound requests and cryptographically signs the originating user context. This prevents downstream tampering. A Cedar evaluator Lambda function evaluates three independent policy layers sequentially, halting on the first deny.

Table 1: Three-layer Cedar policy evaluation model

Layer What it checks Principal to resource
L1 – Agent-to-tool Whether the invoking agent has a sufficient trust score (1–5), belongs to the correct namespace (for example, payments), and is in the production lifecycle stage Agent to tool
L2 – Agent-to-agent delegation Whether the delegation hop count is within the hard limit of five, and whether requested tasks are a subset of the target agent’s registered capabilities Agent to agent
L3 – Originating user authorization Whether the human who initiated the chain has the required role (for example, admin), has completed MFA, and is within the allowed delegation depth Agent to tool (user in context)

Architecture

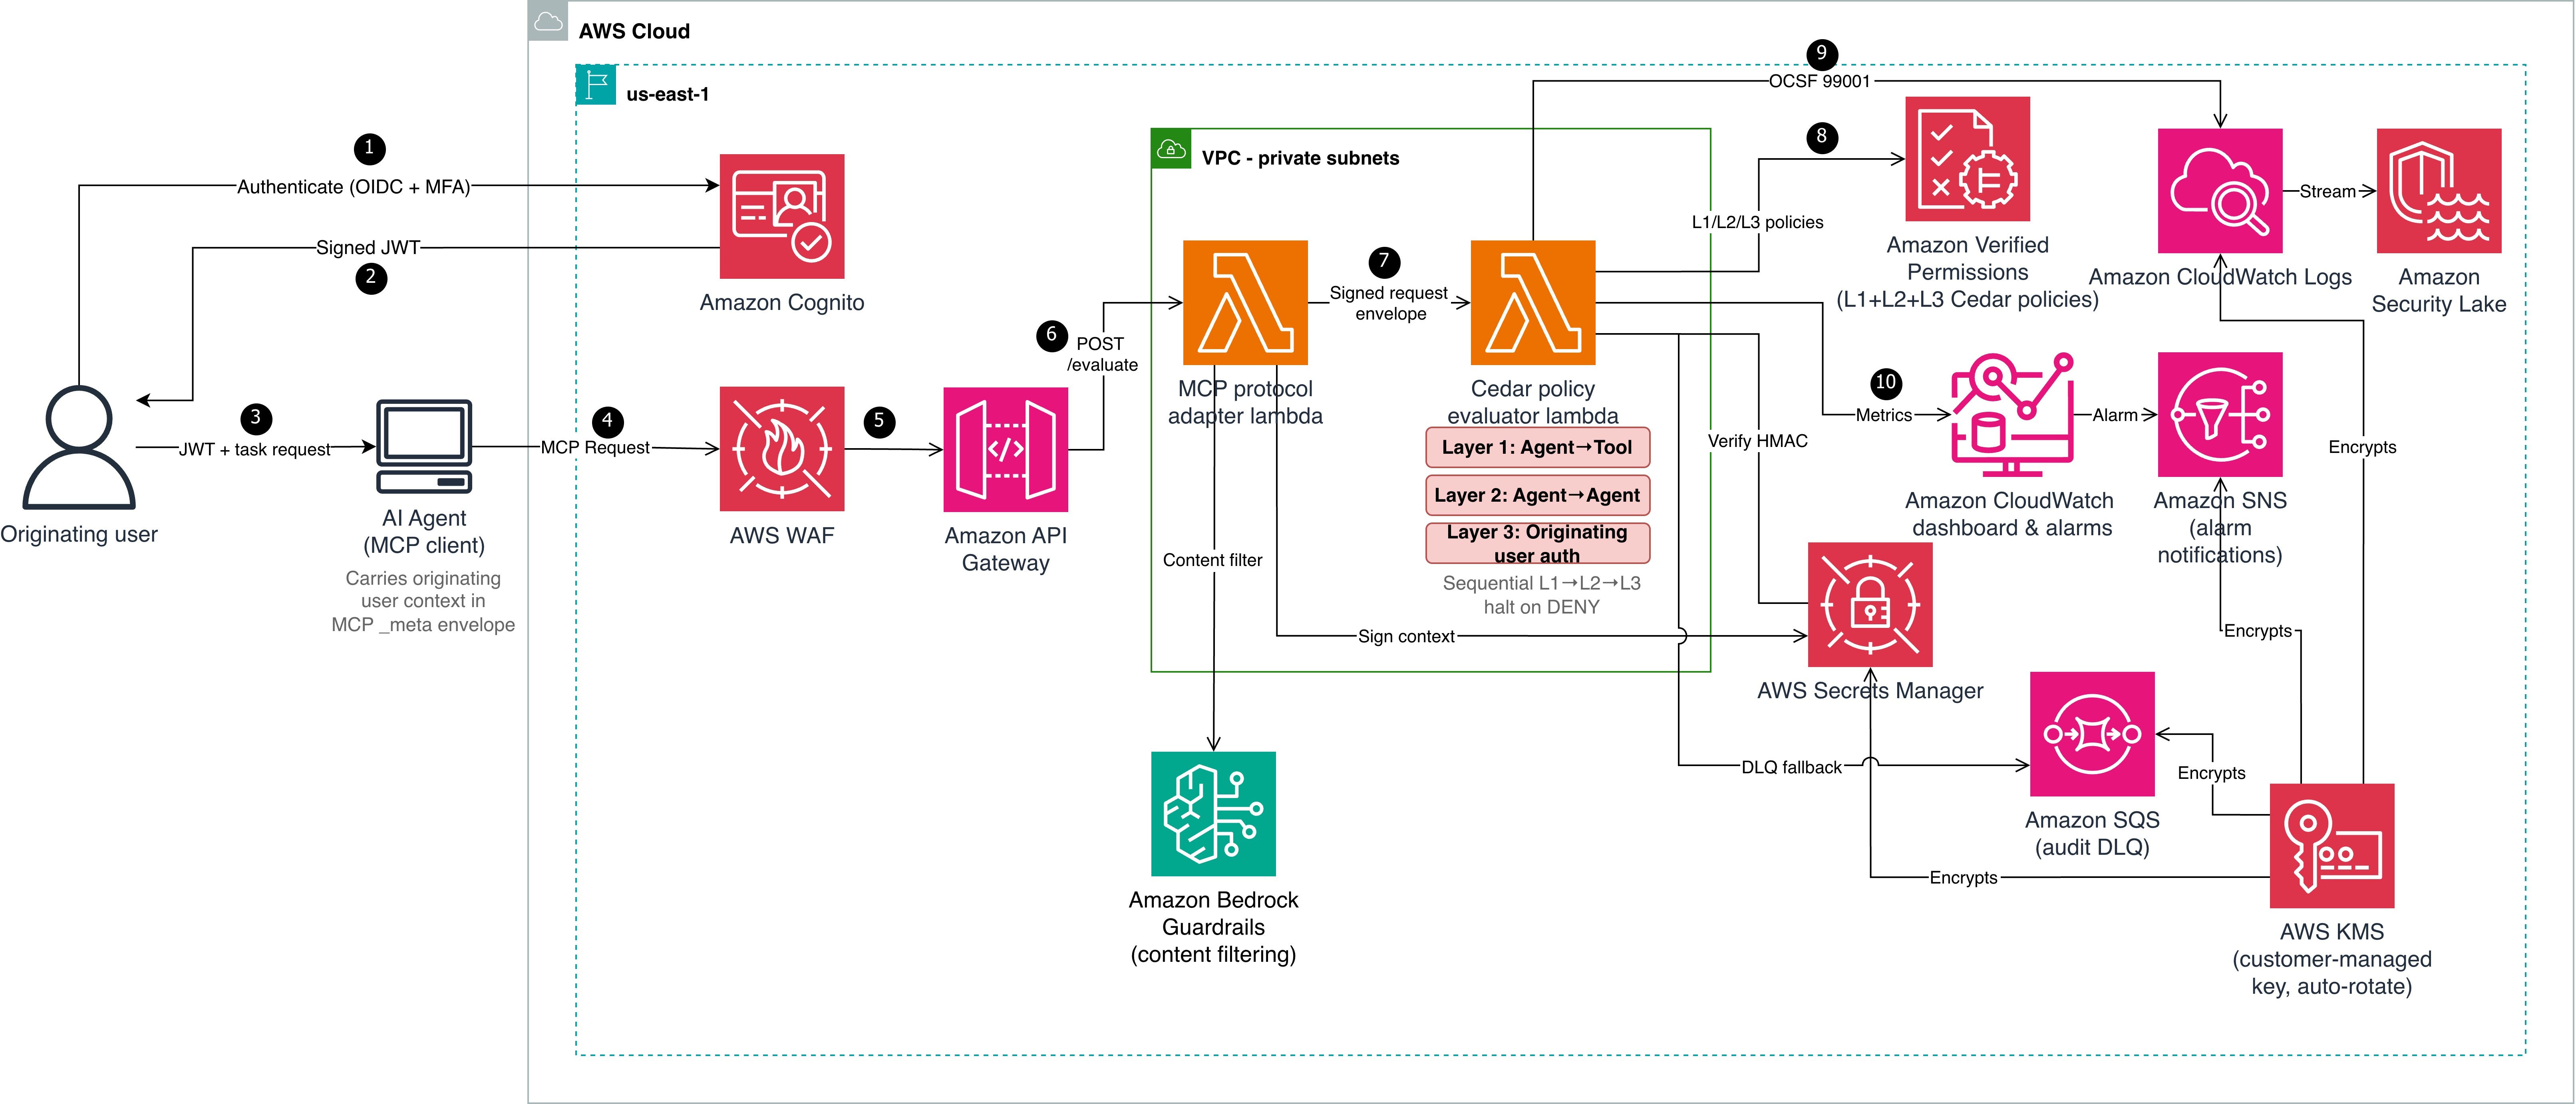
Cedar evaluates authorization but doesn’t establish identity. Before Cedar can evaluate context.originating_user.role or context.originating_user.mfa_verified, a trusted authentication layer must establish the user’s identity and produce verifiable claims. Steps 1–3 handle authentication; steps 4–10 handle authorization. The architecture shown in Figure 1 is described in the following lists:

Authentication (steps 1–3)

  1. The originating user authenticates with an OIDC-compliant identity provider (in this reference implementation, Amazon Cognito with TOTP multi-factor authentication (MFA)). The identity provider (IdP) issues a signed JSON Web Token (JWT) containing claims such as sub, role, amr (authentication methods), and session_id.
  2. Amazon Cognito returns the signed JWT to the user.
  3. The user passes the JWT and task request to the AI agent (MCP client). The agent carries the originating user context in the MCP _meta envelope.

Authorization pipeline (steps 4–10)

  1. The AI agent sends a Model Context Protocol (MCP) request to AWS WAF, which filters using CommonRuleSet, SQLiRuleSet, rate limiting, and body size constraints.
  2. Amazon API Gateway (with Amazon Cognito authorizer) verifies the JWT signature against the user pool’s public keys and rejects invalid or expired tokens. Valid requests are forwarded to the MCP protocol adapter Lambda function, which applies Amazon Bedrock Guardrails content filtering.
  3. The adapter extracts verified claims from the token and maps them to Cedar context attributes:
    1. JWT role claim : context.originating_user.role
    2. JWT amr includes MFA method: context.originating_user.mfa_verified = true
    3. JWT sub: context.originating_user.user_id
    4. JWT sid: context.originating_user.session_id
    5. JWT amr claim: context.originating_user.authentication_method

    The adapter then computes an HMAC-SHA256 signature over the user context (user_id, role, mfa_verified, authentication_method, and session_id in canonical order) using a key from AWS Secrets Manager.

  4. The adapter constructs a signed request envelope and invokes the Cedar evaluator Lambda function.
  5. The evaluator verifies the HMAC-SHA256 signature, retrieves L2 and L3 Cedar policies from Amazon Verified Permissions, and evaluates all three layers (L1, L2, and L3), halting on the first deny.
  6. The evaluator emits an Open Cybersecurity Schema Framework (OCSF) 99001 audit event to Amazon CloudWatch Logs. Failed emissions fall back to an Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ).
  7. Amazon CloudWatch dashboards and alarms monitor evaluation latency, deny rates, and DLQ depth. Alarm notifications route through Amazon Simple Notification Service (Amazon SNS).

Context integrity through delegation hops

Two mechanisms work together to protect identity across hops:

  • Hash-based Message Authentication Code (HMAC-SHA256) ensures integrity and authenticity. Every downstream evaluator verifies this signature before trusting the context.
  • OAuth 2.0 Token Exchange (RFC 8693) sets delegation scope using the on-behalf-of (OBO) pattern. When the orchestrator delegates to a downstream agent (data-bot), it exchanges the original token for a scoped OBO token that records who’s acting on behalf of whom and with what authority. The Cedar policies (detailed in Step 2: Three-layer policies) then check whether that scoped delegation is permitted and verify the originating user claims carried in the OBO token. Token exchange limits each downstream agent to only the delegated task’s scope instead of passing through the full original token. For enterprise deployments, use token exchange alongside HMAC. OAuth tracks who is acting on behalf of whom and with what scope. HMAC verifies that the context hasn’t been tampered with and came from a trusted source.

Prerequisites

The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:

git clone https://github.com/aws-samples/sample-cedar-agentic-ai-authorization.git
cd sample-cedar-agentic-ai-authorization

Verify that you have the following:

Walkthrough

In this walkthrough, you define the Cedar entity schema and policies, deploy the infrastructure with AWS CDK, and integrate your identity provider.

To define the Cedar entity schema

In this step, you define a schema with two entity types (Agent and Tool) and two actions (invoke_tool and delegate_task) in the AgentAuthz namespace. Notice that there is no User entity. Instead, you carry the originating user’s identity in the evaluation context record, which is a structured data object passed alongside each authorization request.

{
  "AgentAuthz": {
    "entityTypes": {
      "Agent": {
        "shape": {
          "type": "Record",
          "attributes": {
            "trust_level": { "type": "Long", "required": true },
            "namespace": { "type": "String", "required": true },
            "registered_capabilities": {
              "type": "Set", "element": { "type": "String" }, "required": true
            },
            "lifecycle_stage": { "type": "String", "required": true }
          }
        }
      },
      "Tool": {
        "shape": {
          "type": "Record",
          "attributes": {
            "namespace": { "type": "String", "required": true },
            "risk_level": { "type": "String", "required": true }
          }
        }
      }
    },
    "actions": {
      "invoke_tool": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Tool"] }
      },
      "delegate_task": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Agent"] }
      }
    }
  }
}

This schema is deployed to an Amazon Verified Permissions policy store by the VerifiedPermissionsStack CDK stack. In the reference implementation, the schema file is located at cedar-entity-schema.json.

Agent topology and attributes

The following tables show the agents and tools registered in this reference implementation, along with the attributes the Cedar evaluator function retrieves from the entity store. The test scenarios that follow trace requests through this topology.

Table 2: Agent attributes

Entity Type trust_level namespace lifecycle_stage registered_capabilities
orchestrator Agent 5 orchestration production

delegate_task

route_request

finance-agent Agent 3 payments production

process_payment

refund

data-bot Agent 4 data production

query_records

delete_records

Table 3: Tool attributes

Tool namespace risk_level
process_payment payments medium
delete_records data high
query_records data low

The orchestrator can delegate to both data-bot and finance-agent. Each agent can only invoke tools within its registered capabilities. The test scenarios below trace requests through these delegation paths.

To create three-layer Cedar policies

The following policies are deployed to the same Verified Permissions policy store. In the reference implementation, policy files are located under cedar/policies/ organized by layer: layer1-agent-to-tool/, layer2-agent-to-agent/, and layer3-originating-user-auth/.

Layer 1 (agent-to-tool): This policy permits the finance-agent to invoke the process_payment tool only when three conditions are met: the agent’s trust score is at least 3, it belongs to the payments namespace, and it’s deployed in the production lifecycle stage. If any condition fails, the request is denied. The agent’s trust_level, namespace, and lifecycle_stage aren’t self-reported in a production deployment. Instead, the evaluator retrieves these attributes from the Verified Permissions entity store using the agent_id as a lookup key.

Important: The reference implementation accepts these values from the request payload for simplicity. Production deployments must validate agent attributes against an authoritative source to prevent a compromised agent from escalating its own trust.

The trust_level attribute uses a 1–5 integer scale that represents an agent’s verified maturity: 1 for newly registered and untested agents, 3 for agents that have passed integration testing and security review, and 5 for agents with a proven production track record. Organizations assign trust levels through their agent promotion pipeline, not through self-declaration. The lifecycle_stage attribute (development, staging, production) prevents pre-production agents from invoking production tools, even if they have the correct namespace and trust score.

// L1-001: Finance agent can invoke payment tools
permit(
  principal == AgentAuthz::Agent::"finance-agent",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"process_payment"
) when {
  principal.trust_level >= 3 &&
  principal.namespace == "payments" &&
  principal.lifecycle_stage == "production"
};

Layer 2 (agent-to-agent delegation) enforces depth limits and capability constraints. The orchestrator agent delegates tasks to data-bot only when the delegation chain is three hops or fewer and the requested capabilities are a subset of data-bot’s registered capabilities. A separate forbid policy (L2-004) enforces a hard system-wide limit of five hops regardless of which agents are involved.

// L2-002: Orchestrator can delegate to data agent
permit(
  principal == AgentAuthz::Agent::"orchestrator",
  action == AgentAuthz::Action::"delegate_task",
  resource == AgentAuthz::Agent::"data-bot"
) when {
  context.delegation_depth <= 3 &&
  context.target_capabilities.containsAll(context.requested_capabilities)
};

Layer 3 (originating user authorization) keeps the agent as the principal, but the policy evaluates context.originating_user to validate the human who initiated the request. data-bot invokes the delete_records tool only when the originating user has the admin role, has verified MFA, and the delegation chain is at most two hops deep. Without this layer, an agent with the right capabilities could invoke destructive tools regardless of who initiated the request.

// L3-001: High-risk tool (delete_records) requires admin + MFA
permit(
  principal == AgentAuthz::Agent::"data-bot",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"delete_records"
) when {
  context.originating_user.role == "admin" &&
  context.originating_user.mfa_verified == true &&
  context.delegation_depth <= 2
};

Key design point: The principal remains the agent, not a user entity. The user’s role and MFA status are checked through context attributes, keeping the schema to two entity types and two actions.

Integrate your IdP

The reference implementation uses Amazon Cognito with TOTP MFA, but most OIDC-compliant providers (Okta, Microsoft Entra ID, Auth0, or AWS IAM Identity Center) work with this pattern. The authentication-to-signing flow is described in the preceding Authentication before authorization section. To use a different IdP, replace the Cognito authorizer on API Gateway with a Lambda or JWT authorizer for your IdP’s issuer URL. Cedar policies remain unchanged.

Deploy the infrastructure with AWS CDK

The reference implementation deploys five CloudFormation stacks: KmsStack, VerifiedPermissionsStack, LambdaStack, SecurityLakeStack, and MonitoringStack. The following commands deploy the stacks in dependency order:

cdk deploy KmsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy VerifiedPermissionsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy LambdaStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy SecurityLakeStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy MonitoringStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID

Test the solution

Three end-to-end scenarios validate the evaluation model across different user roles, MFA states, and delegation depths. To run the tests:

  1. Set the API endpoint from the deployment output:
export API_ENDPOINT=$(aws cloudformation describe-stacks --stack-name LambdaStack \
  --query "Stacks[0].Outputs[?OutputKey=='ApiEndpoint'].OutputValue" --output text)

  1. Run the end-to-end tests:
.venv/bin/python -m pytest tests/e2e/ -v -s

The end-to-end tests cover the three scenarios described in the following sections. Each test sends a request through the deployed API and validates the per-layer authorization decisions.

Scenario A: Layer 3 enforcement

A support-role user (no MFA) requests record deletion through orchestrator and data-bot.

Layer Decision Reason
L1: Agent-to-tool PERMIT data-bot has trust level 4, namespace data, and lifecycle production
L2: Agent-to-agent PERMIT orchestrator is authorized to delegate to data-bot, depth within limits
L3: Originating user DENY User role is support, not admin; MFA not verified
Overall DENY Denying layer: L3

Without Layer 3, this request would have been permitted based on agent capabilities alone, demonstrating why originating user authorization is essential.

Scenario B: Authorized admin request

An admin user with MFA requests the same operation through the same chain.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 PERMIT Delegation path authorized
L3 PERMIT Role is admin, MFA verified, depth is less than or equal to 2
Overall PERMIT All three layers permit

Scenario C: Delegation depth limit

An admin with MFA requests the same operation, but the delegation chain has six hops. This scenario tests the Layer 2 depth constraint independently of user authorization.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 DENY Depth of six exceeds the hard limit of five
Overall DENY Denying layer: L2 (L3 not evaluated – halt)

Even an authorized admin can’t bypass the delegation depth constraint.

Alignment with the security principles for agentic AI

The AWS Office of the CISO published Four security principles for agentic AI systems. The following table shows how this solution maps to each principle.

Principle How the solution implements it
Secure development lifecycle across components Property-based testing (Hypothesis) for adversarial input fuzzing, Cedar policy formal verification with strict schema validation, end-to-end scenarios testing policy bypass and privilege escalation paths, and infrastructure-as-code (IaC) with AWS CDK.
Traditional security controls remain applicable AWS WAF, Amazon VPC isolation, AWS Key Management Service (AWS KMS) encryption, Amazon Cognito MFA, and Secrets Manager;
NIST SP 800-53 control mapping.
Deterministic external controls (security box) Three-layer Cedar evaluation runs outside the agent’s reasoning loop in a separate Lambda function.
HMAC-signed context prevents tampering.
Verified Permissions (the managed Cedar evaluation service) enforces L2 and L3 at the infrastructure level.
Greater autonomy earned through evaluation trust_level and lifecycle_stage policy attributes calibrate agent capabilities; OCSF 99001 audit events and Amazon CloudWatch dashboards provide the evidence base for expanding autonomy.

Monitoring and audit compliance

Each evaluation produces an OCSF 99001 audit event with request ID, user identity, delegation chain, per-layer decisions, and latency.

The following table maps this implementation to NIST SP 800-53 Rev. 5 controls. Customers are responsible for evaluating whether it meets their compliance requirements.

NIST control Control name How the reference implementation addresses it
AC-4 Information Flow Enforcement User context flows immutably through HMAC-signed envelopes
AC-6 Least Privilege Three-layer evaluation requires both agent capability and user role
AC-6(1) Authorize Access to Security Functions MFA required for high-risk tools in Layer 3
AC-6(5) Privileged Accounts Destructive operations restricted to admin with MFA verified
AU-2 Event Logging Each evaluation is logged as OCSF 99001
AU-3 Content of Audit Records Events include identity, chain, action, resource, decisions, and latency
SI-10 Information Input Validation HMAC verified before evaluation; Amazon Bedrock Guardrails on inbound
IA-2(1) Multi-factor Authentication Layer 3 enforces MFA for high-risk operations
SC-12 Cryptographic Key Management Signing key in Secrets Manager with rotation
SC-28 Protection of Information at Rest Policies in Verified Permissions with STRICT validation

Scaling to multi-account environments

Deploy the Cedar policy store in a central security account and use cross-account IAM roles for workload accounts to call verifiedpermissions:IsAuthorized. Use AWS Organizations service control policies (SCPs) to prevent workload accounts from creating their own policy stores. For standardizing user identity attributes across the organization, consider IAM Identity Center or a centralized OIDC provider that issues consistent claims to your workload accounts. This helps ensure that the context.originating_user attributes are uniform across accounts and agents.

For production deployments, consider extending this pattern with human-in-the-loop escalation for borderline denials, multi-tenant Cedar policy isolation, and Amazon Simple Storage Service (Amazon S3)-backed dynamic policy hot-reload for emergency tool shutdowns.

Clean up

To avoid ongoing charges, delete the deployed resources:

cdk destroy MonitoringStack SecurityLakeStack
cdk destroy LambdaStack
cdk destroy VerifiedPermissionsStack
cdk destroy KmsStack
aws logs delete-log-group --log-group-name /cedar-evaluator/audit  # if RETAIN policy

Conclusion

Multi-agent AI systems need authorization boundaries at every delegation hop. The three-layer Cedar policy model with OAuth 2.0 authentication provides that protection while maintaining least-privilege access. Combining a trusted IdP (AuthN) with Cedar policy evaluation (AuthZ) creates an authorization boundary around each tool invocation, verifying agent capability (L1), delegation path (L2), and originating user authority (L3). The pattern works with an OIDC-compliant IdP and a compute platform that can call Amazon Verified Permissions. Clone the reference implementation and adapt the Cedar policies to your organization’s requirements. For more information, see the Cedar policy language documentation and the Amazon Verified Permissions User Guide.

References

If you have feedback about this post, submit comments in the Comments section below.


Dhananjay Karanjkar

Dhananjay Karanjkar

Dhananjay is a Senior Lead Consultant at AWS Professional Services, specializing in agentic AI systems, multi-agent orchestration, and generative AI security. He holds two US patents and serves as a Responsible AI Champion, with a background spanning financial services, enterprise consulting, and enterprise-scale AI delivery. When not architecting AI solutions, he trains for triathlons, paints oil portraits, and is an avid reader.

Unlocking the Cloudflare app ecosystem with OAuth for all

Post Syndicated from Sam Cabell original https://blog.cloudflare.com/oauth-for-all/

Cloudflare provides services that help run 20% of the web, but we don’t do it alone. Developers on our platform use a myriad of tools and services from other companies too. Cloudflare provides a rich API for our platform that enables developers to create automations, CI/CD, and integrations that glue together the various parts of their infrastructure. Earlier this month, we announced self-managed OAuth, making it easier for customers to create and manage their own OAuth clients for delegated access to the Cloudflare API.

Cloudflare isn’t new to OAuth. If you’ve used Wrangler, or used integrations from partners like PlanetScale, then you’ve already used it. However, until now, third-party OAuth was only available through a small number of manually onboarded integrations, and was not available to developers more broadly. That meant developers building their own integrations had to rely on API tokens, which are harder to manage and a poor fit for many delegated application flows. 

Over the last year, we onboarded a growing number of early partners while improving the consent, revocation, and security model behind Cloudflare OAuth. But as our Developer Platform grew and agentic tools drove demand for delegated access, it became clear that opening up OAuth to all customers was critical to the success of our platform. 

With self-managed OAuth, developers can now offer a standard OAuth flow where customers grant scoped access directly, making it easier to build SaaS integrations, internal developer platforms, and agentic tools while giving users clearer consent, easier revocation, and more control over what an application can do.

Scaling the ecosystem securely

While our earlier OAuth solution was sufficient for a small number of carefully managed partners, we realized that our permissions model, our consent experience, and our ways of mitigating potential abuse vectors were not mature enough. 

Earlier this year we updated our consent experience to make it clearer which application is requesting access, and what permissions it will receive. We also added revocation to the dashboard so developers can easily control which applications have access to their data, and made app ownership more visible to prevent OAuth phishing attacks. 

Opening self-managed OAuth to all customers also required major upgrades to our underlying OAuth engine. This process required a large amount of planning to do with minimal user interruption, while also ensuring data stability and security.

Planning the upgrade to our OAuth engine

Years ago, we deployed Hydra, an open-source OAuth engine, to power Cloudflare OAuth under the hood. That deployment served us well when usage was limited, but as the developer platform grew and agentic workflows became more common, it became clear that we needed a major upgrade to unlock new capabilities and improve performance. 

As we planned the upgrade, we decided to do two smaller sequential upgrades rather than doing one large upgrade.  First, we would move to the latest 1.X release, evaluate any behavior or performance changes, and then proceed with the 2.X upgrade.

During our upgrade planning, it became clear that even the 1.X upgrade would still impact customers because the Hydra database required extensive schema migrations that:

  1. Created indexes in a manner that would claim an exclusive lock on critical tables, preventing active users from performing important OAuth operations 

  2. Added columns to critical tables, and moved other columns to new tables

There was also a quirk in the version of Hydra we were using in which the SDK would perform SELECT * operations, causing deserialization issues with the schema changes.

To prevent user impact, we rewrote the SQL migrations to use features such as CREATE INDEX CONCURRENTLY, and built a custom version of Hydra which selected explicit columns rather than SELECT *.

With the latest 1.X upgrade planned out, we now needed to create a plan for the even larger 2.X upgrade. We identified three potential options, and weighed the benefits and drawbacks of each one. Doing an in-place upgrade was not going to work for us, due to the sheer amount of schema changes the major version bump brought with it. We decided that a blue-green strategy would work, but there was more that needed to be done than simply flipping a switch to start using the new version. The upgrade and migration process would take multiple hours, and we needed the system to continue functioning correctly in that time window.

The first blue-green option would involve disabling writes to the database, preventing any new authorizations from occurring. This means they would not be lost in the transition, but it also meant that nobody would be able to use existing OAuth apps unless they already had a valid credential. It also presented another large problem: if users needed to revoke access from an application for any reason, it would not be possible while the upgrade was being performed.

To combat these issues, we came up with a way to leave writes to the database enabled, at the cost of losing some of them in the switch to the green version. The first thing to solve was minimizing the number of writes for new tokens. There was an operational lever we pulled: increasing the expiry time of tokens to multiple hours. This would allow apps that received new tokens before the upgrade to continue using them without needing to refresh.

With reducing writes solved, we needed to come up with a way to not lose any revocations our users performed during the upgrade window. To do this, we created a queue system (using Cloudflare Queues!) which, after a revocation event, would have a record written into the queue with information about that revocation. This would allow us to drain the queue with the database flipped to the green version, replaying all revocation events that took place in the time window in which they would have been lost. This was critical to get right, otherwise applications that users had revoked would inadvertently have their access restored.

Executing the upgrade

Upgrading to 1.X

From an operational point of view, our first upgrade to the last 1.X release went off without any hitches. Our custom database migrations ran faster than we expected, with no user impact. We had to do a hard cutover to the new version because the old version was unable to introspect tokens that were created by the newer version.

After the cutover, we saw an increase in refresh token errors that we had not seen before. This ended up being due to stricter refresh invalidation behaviors in the new version; if a refresh token was reused, Hydra would invalidate the whole access and refresh token chain. This is problematic for Wrangler and MCP clients. These clients both have a high request volume, and a single reused refresh token would invalidate the entire session.

We mitigated this by adding refresh token coalescing behavior to our Worker which routes OAuth traffic to the correct destination. This allowed us to briefly cache the refresh token request before it reached Hydra, so that if we detected a retry we could short-circuit the request and respond without invalidating the tokens. Fortunately, 2.X versions of Hydra have a configurable “refresh token grace period”, which resolves this by allowing a refresh token to be retried for a period of time without invalidating the whole chain.

Upgrading to 2.X

Since multiple hours of high user-facing impact would not be acceptable, we had our blue-green upgrade strategy set. At a high level, this sounds simple; the migrations would run on a copy of our production database, and then cut over along with the new Hydra version after they complete. In reality, there were a lot more moving parts:

  • Enable revocation replay capture queue

  • Copy and restore our database to the new target

  • Targeted data cleanup — existing data violated some new constraints introduced in the newer versions, which could prevent migrations from succeeding

  • Perform cutovers on the Hydra service along with two additional critical internal systems simultaneously to prevent any errors

  • Post-cutover monitoring and validation


We chose an upgrade window when Hydra had the lowest request volume per second to minimize lost token writes. Other than some timeout tuning, our production migrations ran well against the new database: the net runtime in production was approximately three hours. After the migrations completed, we carefully rolled out the new version of the Hydra service, along with two additional system configs to flip our systems to use the new SDK version.

Shortly after cutting traffic over, we observed that a data cleanup job in our authorization service (which relies on the Hydra consent session API) was being overeager in its purging of OAuth policy data. After investigation, we discovered that there was an issue in one of the Hydra migrations that corrupted the state of certain valid OAuth sessions, which resulted in the migration marking them as invalid. The valid sessions being corrupted caused a disagreement between Hydra and our authorization service, manifesting as an increase in 403s. To mitigate this, we did data restorations and began work on improvements for OAuth authorization behaviors to remove reliance on static policy data.

Beyond the data cleanup issue, there were some additional small fixes more driven by specific client behaviors which we landed quickly. 

With the Hydra version upgrade complete, OAuth traffic has remained stable with improved system performance and reliability for our customers. It also brought production onto the same foundation our newer OAuth APIs had already been validated against in staging, clearing the way for our self-managed OAuth release on June 3

Performance improvements

After completing a large upgrade like this, it is always rewarding and illuminating to look at some broad metrics about the impact. We gathered additional metrics during the database migrations, and observed considerable performance improvements after the upgrade was complete.

Database

Metric Approx. Value
Rows updated 132.5M
Rows inserted 114.7M
Temp bytes 136.97GB
Transaction commits 22.2k

Hydra performance

Metric (avg) Before After Change
API P95 185ms 101ms -45%
RSS memory 888MB 763MB -14%
Go heap alloc 449MB 271MB -40%
Goroutines 4015 3076 -23%
CPU 1.07 cores 0.67 cores -37%

Self-managed OAuth for all

Opening up OAuth to all customers is an important step toward a broader Cloudflare app ecosystem. Today, any Cloudflare customer can create their own OAuth applications and build integrations on top of Cloudflare. We’re extremely excited to launch Cloudflare self-managed OAuth for all. 

To get started, take a look at our documentation or jump straight to the OAuth apps page in the dashboard and create your first OAuth app.

Building fine-grained authorization using Amazon Cognito, API Gateway, and IAM

Post Syndicated from Artem Lovan original https://aws.amazon.com/blogs/security/building-fine-grained-authorization-using-amazon-cognito-api-gateway-and-iam/

June 5, 2021: We’ve updated Figure 1: User request flow.


Authorizing functionality of an application based on group membership is a best practice. If you’re building APIs with Amazon API Gateway and you need fine-grained access control for your users, you can use Amazon Cognito. Amazon Cognito allows you to use groups to create a collection of users, which is often done to set the permissions for those users. In this post, I show you how to build fine-grained authorization to protect your APIs using Amazon Cognito, API Gateway, and AWS Identity and Access Management (IAM).

As a developer, you’re building a customer-facing application where your users are going to log into your web or mobile application, and as such you will be exposing your APIs through API Gateway with upstream services. The APIs could be deployed on Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), AWS Lambda, or Elastic Load Balancing where each of these options will forward the request to your Amazon Elastic Compute Cloud (Amazon EC2) instances. Additionally, you can use on-premises services that are connected to your Amazon Web Services (AWS) environment over an AWS VPN or AWS Direct Connect. It’s important to have fine-grained controls for each API endpoint and HTTP method. For instance, the user should be allowed to make a GET request to an endpoint, but should not be allowed to make a POST request to the same endpoint. As a best practice, you should assign users to groups and use group membership to allow or deny access to your API services.

Solution overview

In this blog post, you learn how to use an Amazon Cognito user pool as a user directory and let users authenticate and acquire the JSON Web Token (JWT) to pass to the API Gateway. The JWT is used to identify what group the user belongs to, as mapping a group to an IAM policy will display the access rights the group is granted.

Note: The solution works similarly if Amazon Cognito would be federating users with an external identity provider (IdP)—such as Ping, Active Directory, or Okta—instead of being an IdP itself. To learn more, see Adding User Pool Sign-in Through a Third Party. Additionally, if you want to use groups from an external IdP to grant access, Role-based access control using Amazon Cognito and an external identity provider outlines how to do so.

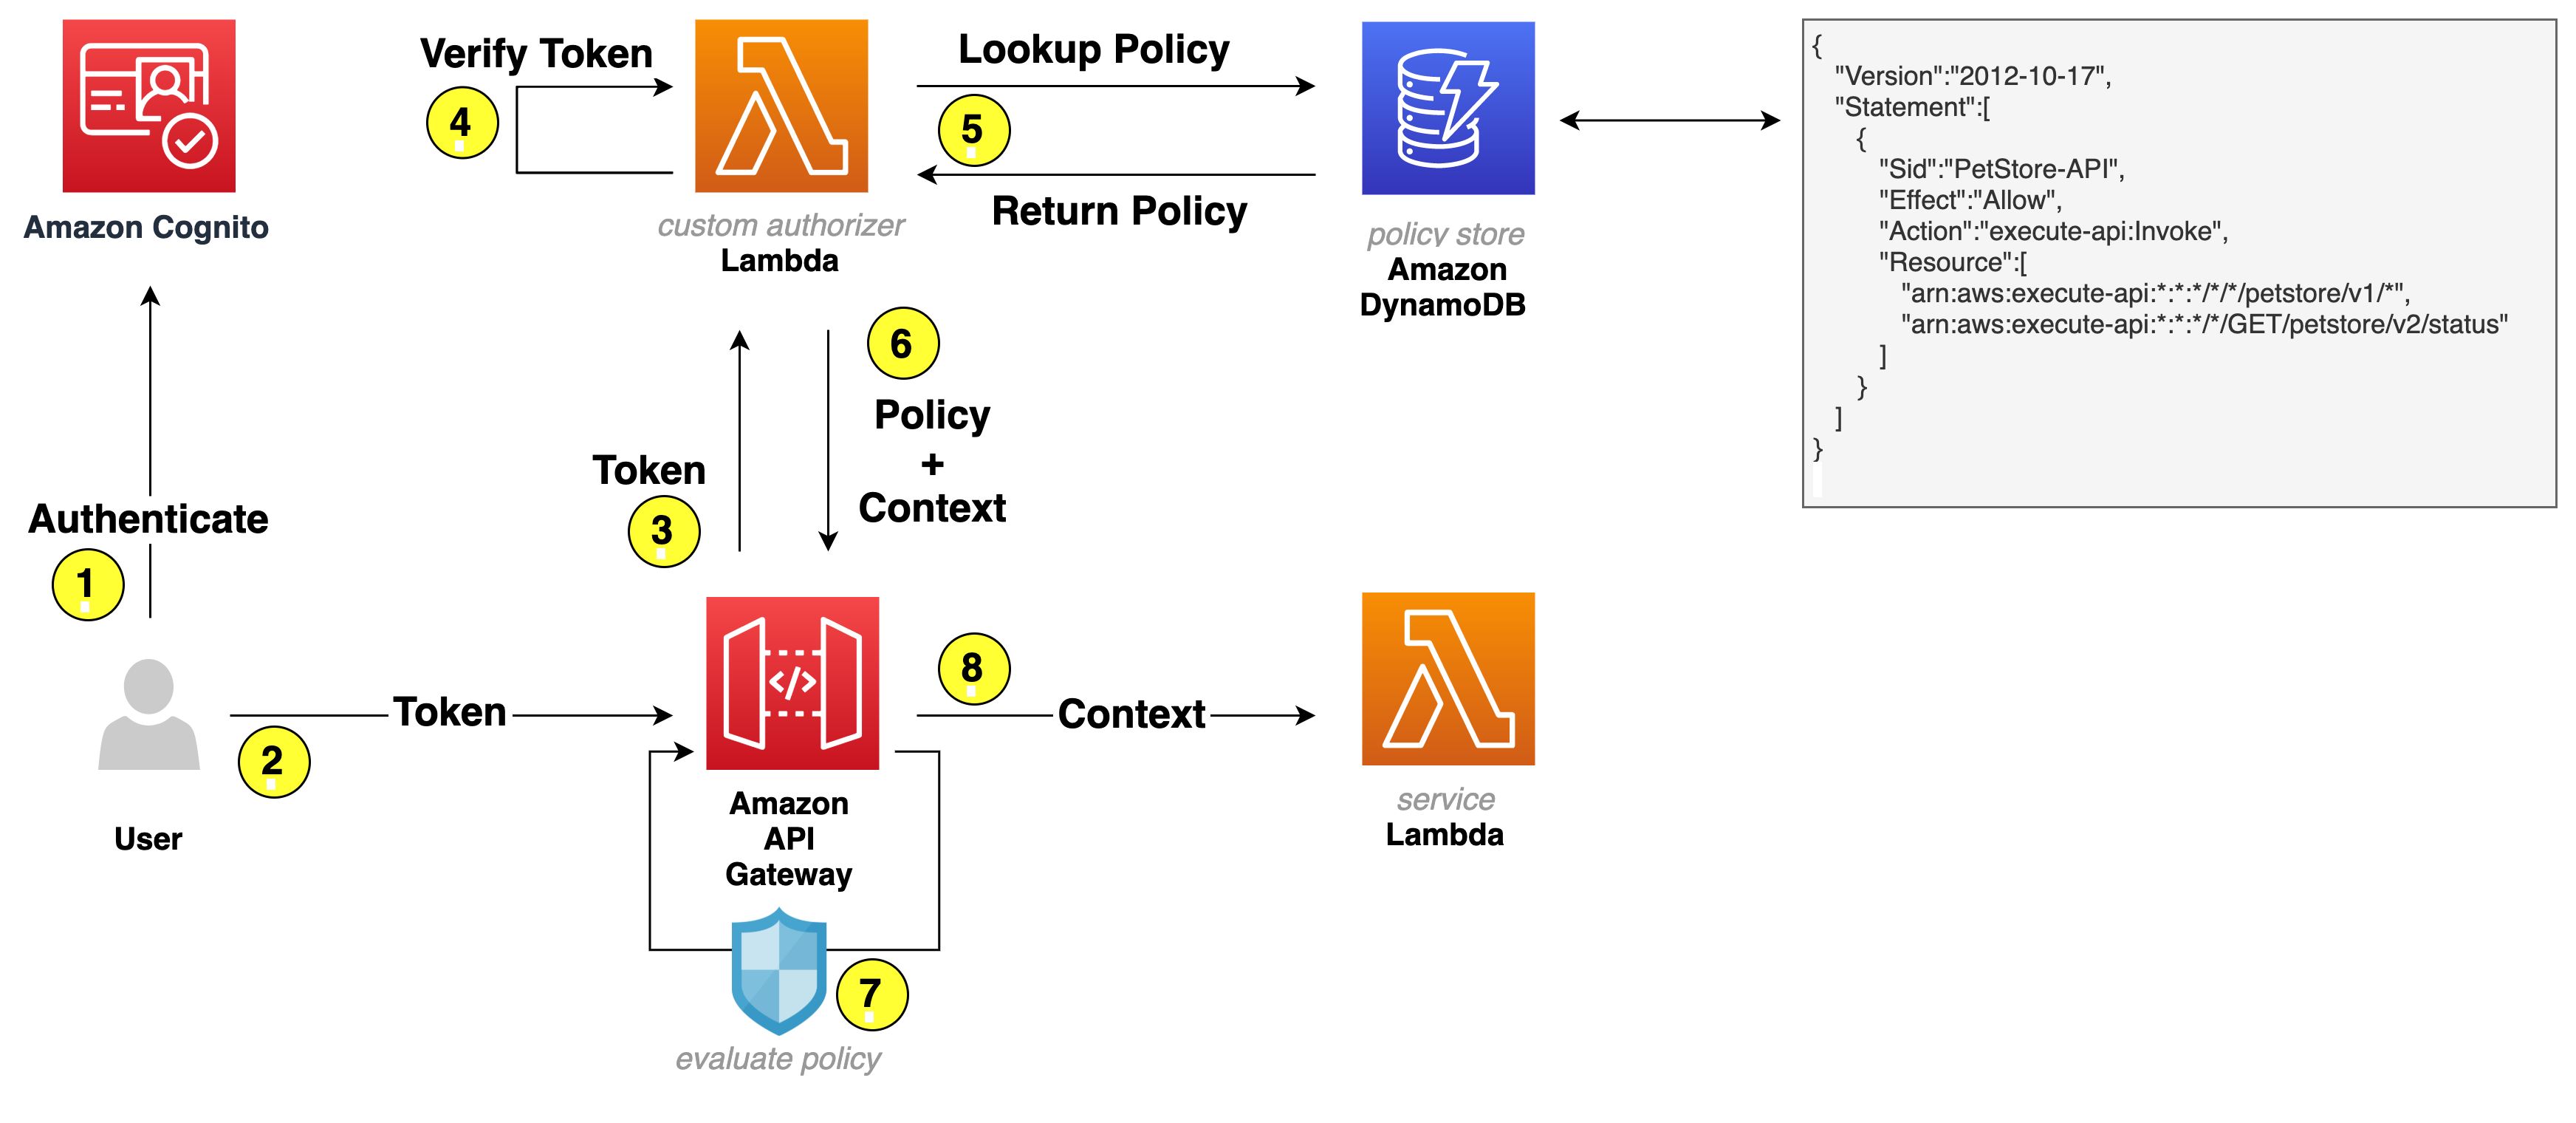
The following figure shows the basic architecture and information flow for user requests.

Figure 1: User request flow

Figure 1: User request flow

Let’s go through the request flow to understand what happens at each step, as shown in Figure 1:

  1. A user logs in and acquires an Amazon Cognito JWT ID token, access token, and refresh token. To learn more about each token, see using tokens with user pools.
  2. A RestAPI request is made and a bearer token—in this solution, an access token—is passed in the headers.
  3. API Gateway forwards the request to a Lambda authorizer—also known as a custom authorizer.
  4. The Lambda authorizer verifies the Amazon Cognito JWT using the Amazon Cognito public key. On initial Lambda invocation, the public key is downloaded from Amazon Cognito and cached. Subsequent invocations will use the public key from the cache.
  5. The Lambda authorizer looks up the Amazon Cognito group that the user belongs to in the JWT and does a lookup in Amazon DynamoDB to get the policy that’s mapped to the group.
  6. Lambda returns the policy and—optionally—context to API Gateway. The context is a map containing key-value pairs that you can pass to the upstream service. It can be additional information about the user, the service, or anything that provides additional information to the upstream service.
  7. The API Gateway policy engine evaluates the policy.

    Note: Lambda isn’t responsible for understanding and evaluating the policy. That responsibility falls on the native capabilities of API Gateway.

  8. The request is forwarded to the service.

Note: To further optimize Lambda authorizer, the authorization policy can be cached or disabled, depending on your needs. By enabling cache, you could improve the performance as the authorization policy will be returned from the cache whenever there is a cache key match. To learn more, see Configure a Lambda authorizer using the API Gateway console.

Let’s have a closer look at the following example policy that is stored as part of an item in DynamoDB.

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"PetStore-API",
         "Effect":"Allow",
         "Action":"execute-api:Invoke",
         "Resource":[
            "arn:aws:execute-api:*:*:*/*/*/petstore/v1/*",
            "arn:aws:execute-api:*:*:*/*/GET/petstore/v2/status"
         ],
         "Condition":{
            "IpAddress":{
               "aws:SourceIp":[
                  "192.0.2.0/24",
                  "198.51.100.0/24"
               ]
            }
         }
      }
   ]
}

Based on this example policy, the user is allowed to make calls to the petstore API. For version v1, the user can make requests to any verb and any path, which is expressed by an asterisk (*). For v2, the user is only allowed to make a GET request for path /status. To learn more about how the policies work, see Output from an Amazon API Gateway Lambda authorizer.

Getting started

For this solution, you need the following prerequisites:

  • The AWS Command Line Interface (CLI) installed and configured for use.
  • Python 3.6 or later, to package Python code for Lambda

    Note: We recommend that you use a virtual environment or virtualenvwrapper to isolate the solution from the rest of your Python environment.

  • An IAM role or user with enough permissions to create Amazon Cognito User Pool, IAM Role, Lambda, IAM Policy, API Gateway and DynamoDB table.
  • The GitHub repository for the solution. You can download it, or you can use the following Git command to download it from your terminal.

    Note: This sample code should be used to test out the solution and is not intended to be used in production account.

     $ git clone https://github.com/aws-samples/amazon-cognito-api-gateway.git
     $ cd amazon-cognito-api-gateway
    

    Use the following command to package the Python code for deployment to Lambda.

     $ bash ./helper.sh package-lambda-functions
     …
     Successfully completed packaging files.
    

To implement this reference architecture, you will be utilizing the following services:

Note: This solution was tested in the us-east-1, us-east-2, us-west-2, ap-southeast-1, and ap-southeast-2 Regions. Before selecting a Region, verify that the necessary services—Amazon Cognito, API Gateway, and Lambda—are available in those Regions.

Let’s review each service, and how those will be used, before creating the resources for this solution.

Amazon Cognito user pool

A user pool is a user directory in Amazon Cognito. With a user pool, your users can log in to your web or mobile app through Amazon Cognito. You use the Amazon Cognito user directory directly, as this sample solution creates an Amazon Cognito user. However, your users can also log in through social IdPs, OpenID Connect (OIDC), and SAML IdPs.

Lambda as backing API service

Initially, you create a Lambda function that serves your APIs. API Gateway forwards all requests to the Lambda function to serve up the requests.

An API Gateway instance and integration with Lambda

Next, you create an API Gateway instance and integrate it with the Lambda function you created. This API Gateway instance serves as an entry point for the upstream service. The following bash command below creates an Amazon Cognito user pool, a Lambda function, and an API Gateway instance. The command then configures proxy integration with Lambda and deploys an API Gateway stage.

Deploy the sample solution

From within the directory where you downloaded the sample code from GitHub, run the following command to generate a random Amazon Cognito user password and create the resources described in the previous section.

 $ bash ./helper.sh cf-create-stack-gen-password
 ...
 Successfully created CloudFormation stack.

When the command is complete, it returns a message confirming successful stack creation.

Validate Amazon Cognito user creation

To validate that an Amazon Cognito user has been created successfully, run the following command to open the Amazon Cognito UI in your browser and then log in with your credentials.

Note: When you run this command, it returns the user name and password that you should use to log in.

 $ bash ./helper.sh open-cognito-ui
  Opening Cognito UI. Please use following credentials to login:
  Username: cognitouser
  Password: xxxxxxxx

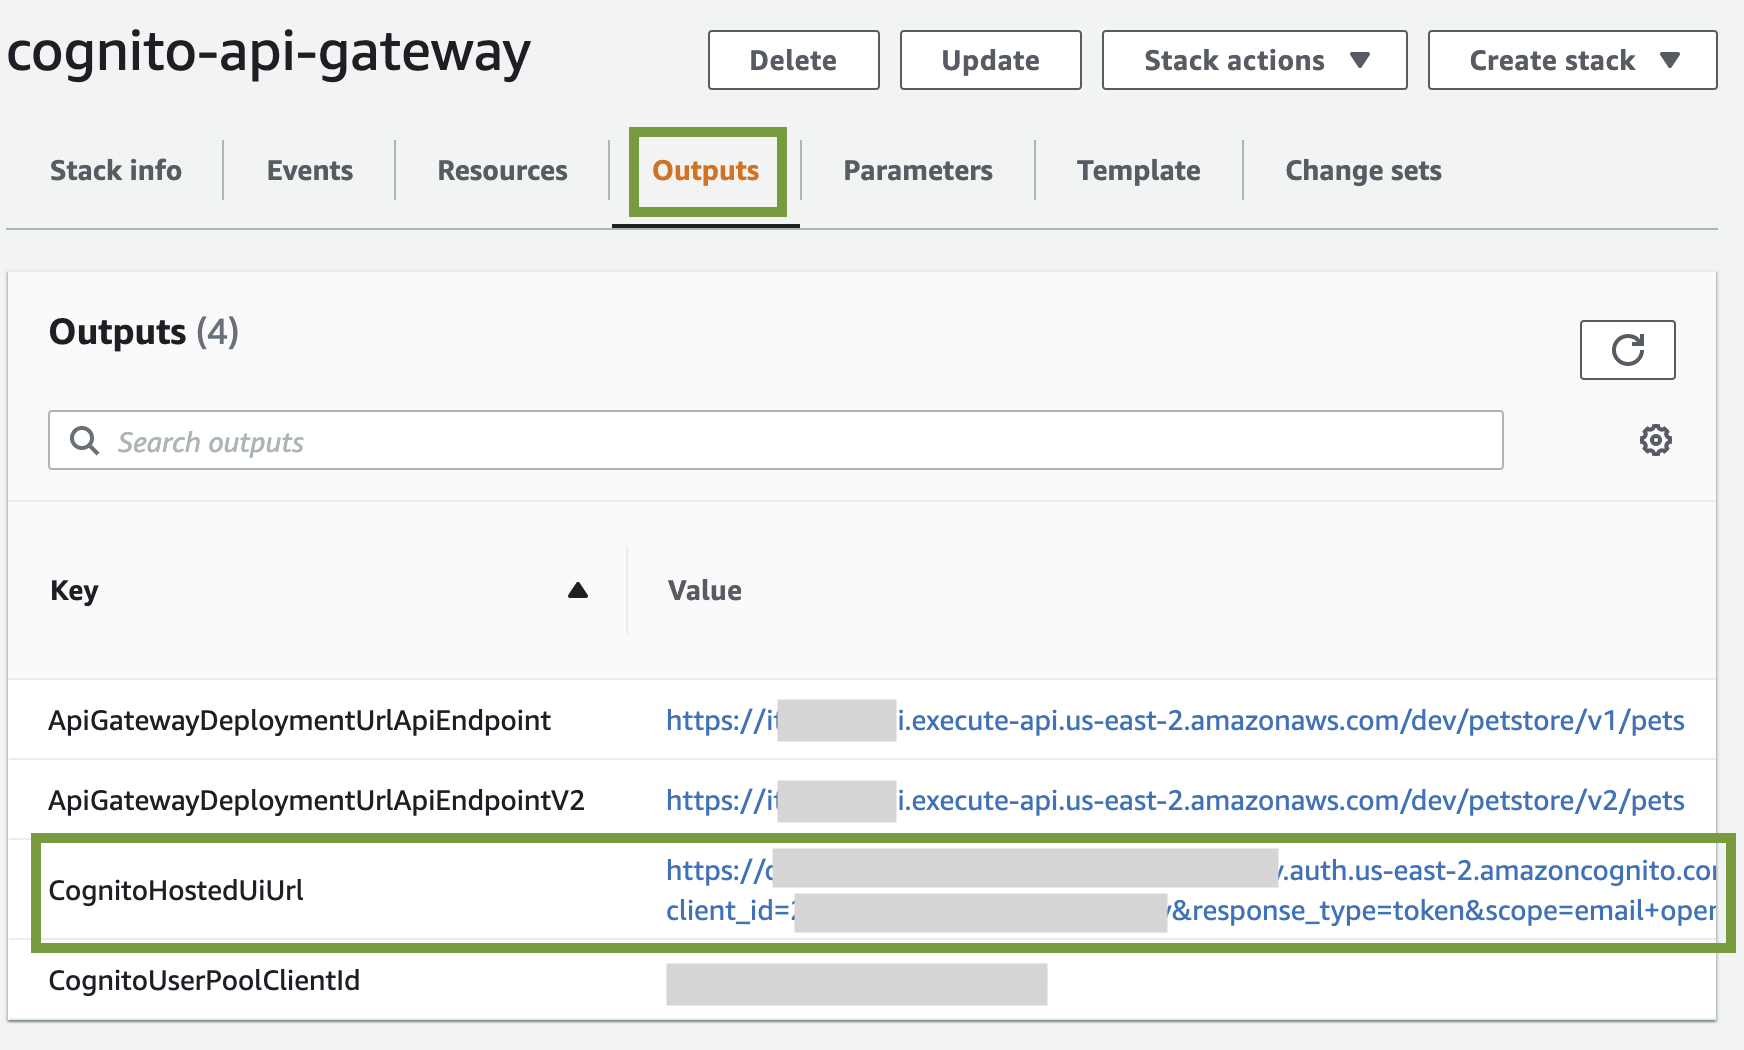
Alternatively, you can open the CloudFormation stack and get the Amazon Cognito hosted UI URL from the stack outputs. The URL is the value assigned to the CognitoHostedUiUrl variable.

Figure 2: CloudFormation Outputs - CognitoHostedUiUrl

Figure 2: CloudFormation Outputs – CognitoHostedUiUrl

Validate Amazon Cognito JWT upon login

Since we haven’t installed a web application that would respond to the redirect request, Amazon Cognito will redirect to localhost, which might look like an error. The key aspect is that after a successful log in, there is a URL similar to the following in the navigation bar of your browser:

http://localhost/#id_token=eyJraWQiOiJicVhMYWFlaTl4aUhzTnY3W...

Test the API configuration

Before you protect the API with Amazon Cognito so that only authorized users can access it, let’s verify that the configuration is correct and the API is served by API Gateway. The following command makes a curl request to API Gateway to retrieve data from the API service.

 $ bash ./helper.sh curl-api
{"pets":[{"id":1,"name":"Birds"},{"id":2,"name":"Cats"},{"id":3,"name":"Dogs"},{"id":4,"name":"Fish"}]}

The expected result is that the response will be a list of pets. In this case, the setup is correct: API Gateway is serving the API.

Protect the API

To protect your API, the following is required:

  1. DynamoDB to store the policy that will be evaluated by the API Gateway to make an authorization decision.
  2. A Lambda function to verify the user’s access token and look up the policy in DynamoDB.

Let’s review all the services before creating the resources.

Lambda authorizer

A Lambda authorizer is an API Gateway feature that uses a Lambda function to control access to an API. You use a Lambda authorizer to implement a custom authorization scheme that uses a bearer token authentication strategy. When a client makes a request to one of the API operations, the API Gateway calls the Lambda authorizer. The Lambda authorizer takes the identity of the caller as input and returns an IAM policy as the output. The output is the policy that is returned in DynamoDB and evaluated by the API Gateway. If there is no policy mapped to the caller identity, Lambda will generate a deny policy and request will be denied.

DynamoDB table

DynamoDB is a key-value and document database that delivers single-digit millisecond performance at any scale. This is ideal for this use case to ensure that the Lambda authorizer can quickly process the bearer token, look up the policy, and return it to API Gateway. To learn more, see Control access for invoking an API.

The final step is to create the DynamoDB table for the Lambda authorizer to look up the policy, which is mapped to an Amazon Cognito group.

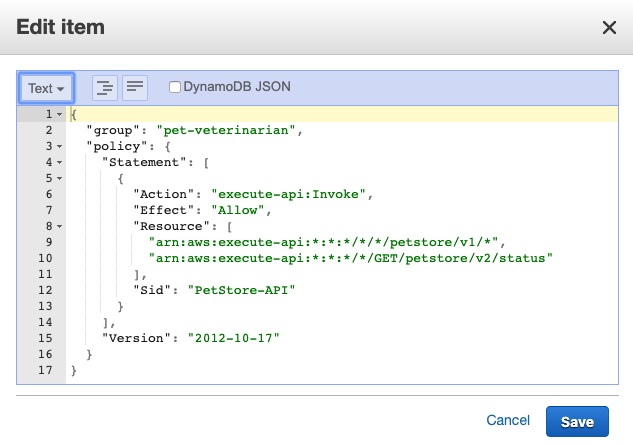
Figure 3 illustrates an item in DynamoDB. Key attributes are:

  • Group, which is used to look up the policy.
  • Policy, which is returned to API Gateway to evaluate the policy.


Figure 3: DynamoDB item

Figure 3: DynamoDB item

Based on this policy, the user that is part of the Amazon Cognito group pet-veterinarian is allowed to make API requests to endpoints https://<domain>/<api-gateway-stage>/petstore/v1/* and https://<domain>/<api-gateway-stage>/petstore/v2/status for GET requests only.

Update and create resources

Run the following command to update existing resources and create a Lambda authorizer and DynamoDB table.

 $ bash ./helper.sh cf-update-stack
Successfully updated CloudFormation stack.

Test the custom authorizer setup

Begin your testing with the following request, which doesn’t include an access token.

$ bash ./helper.sh curl-api
{"message":"Unauthorized"}

The request is denied with the message Unauthorized. At this point, the Amazon API Gateway expects a header named Authorization (case sensitive) in the request. If there’s no authorization header, the request is denied before it reaches the lambda authorizer. This is a way to filter out requests that don’t include required information.

Use the following command for the next test. In this test, you pass the required header but the token is invalid because it wasn’t issued by Amazon Cognito but is a simple JWT-format token stored in ./helper.sh. To learn more about how to decode and validate a JWT, see decode and verify an Amazon Cognito JSON token.

$ bash ./helper.sh curl-api-invalid-token
{"Message":"User is not authorized to access this resource"}

This time the message is different. The Lambda authorizer received the request and identified the token as invalid and responded with the message User is not authorized to access this resource.

To make a successful request to the protected API, your code will need to perform the following steps:

  1. Use a user name and password to authenticate against your Amazon Cognito user pool.
  2. Acquire the tokens (id token, access token, and refresh token).
  3. Make an HTTPS (TLS) request to API Gateway and pass the access token in the headers.

Before the request is forwarded to the API service, API Gateway receives the request and passes it to the Lambda authorizer. The authorizer performs the following steps. If any of the steps fail, the request is denied.

  1. Retrieve the public keys from Amazon Cognito.
  2. Cache the public keys so the Lambda authorizer doesn’t have to make additional calls to Amazon Cognito as long as the Lambda execution environment isn’t shut down.
  3. Use public keys to verify the access token.
  4. Look up the policy in DynamoDB.
  5. Return the policy to API Gateway.

The access token has claims such as Amazon Cognito assigned groups, user name, token use, and others, as shown in the following example (some fields removed).

{
    "sub": "00000000-0000-0000-0000-0000000000000000",
    "cognito:groups": [
        "pet-veterinarian"
    ],
...
    "token_use": "access",
    "scope": "openid email",
    "username": "cognitouser"
}

Finally, let’s programmatically log in to Amazon Cognito UI, acquire a valid access token, and make a request to API Gateway. Run the following command to call the protected API.

$ bash ./helper.sh curl-protected-api
{"pets":[{"id":1,"name":"Birds"},{"id":2,"name":"Cats"},{"id":3,"name":"Dogs"},{"id":4,"name":"Fish"}]}

This time, you receive a response with data from the API service. Let’s examine the steps that the example code performed:

  1. Lambda authorizer validates the access token.
  2. Lambda authorizer looks up the policy in DynamoDB based on the group name that was retrieved from the access token.
  3. Lambda authorizer passes the IAM policy back to API Gateway.
  4. API Gateway evaluates the IAM policy and the final effect is an allow.
  5. API Gateway forwards the request to Lambda.
  6. Lambda returns the response.

Let’s continue to test our policy from Figure 3. In the policy document, arn:aws:execute-api:*:*:*/*/GET/petstore/v2/status is the only endpoint for version V2, which means requests to endpoint /GET/petstore/v2/pets should be denied. Run the following command to test this.

 $ bash ./helper.sh curl-protected-api-not-allowed-endpoint
{"Message":"User is not authorized to access this resource"}

Note: Now that you understand fine grained access control using Cognito user pool, API Gateway and lambda function, and you have finished testing it out, you can run the following command to clean up all the resources associated with this solution:

 $ bash ./helper.sh cf-delete-stack

Advanced IAM policies to further control your API

With IAM, you can create advanced policies to further refine access to your APIs. You can learn more about condition keys that can be used in API Gateway, their use in an IAM policy with conditions, and how policy evaluation logic determines whether to allow or deny a request.

Summary

In this post, you learned how IAM and Amazon Cognito can be used to provide fine-grained access control for your API behind API Gateway. You can use this approach to transparently apply fine-grained control to your API, without having to modify the code in your API, and create advanced policies by using IAM condition keys.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon Cognito forum or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
Author

Artem Lovan

Artem is a Senior Solutions Architect based in New York. He helps customers architect and optimize applications on AWS. He has been involved in IT at many levels, including infrastructure, networking, security, DevOps, and software development.

How to add authentication to a single-page web application with Amazon Cognito OAuth2 implementation

Post Syndicated from George Conti original https://aws.amazon.com/blogs/security/how-to-add-authentication-single-page-web-application-with-amazon-cognito-oauth2-implementation/

In this post, I’ll be showing you how to configure Amazon Cognito as an OpenID provider (OP) with a single-page web application.

This use case describes using Amazon Cognito to integrate with an existing authorization system following the OpenID Connect (OIDC) specification. OIDC is an identity layer on top of the OAuth 2.0 protocol to enable clients to verify the identity of users. Amazon Cognito lets you add user sign-up, sign-in, and access control to your web and mobile apps quickly and easily. Some key reasons customers select Amazon Cognito include:

  • Simplicity of implementation: The console is very intuitive; it takes a short time to understand how to configure and use Amazon Cognito. Amazon Cognito also has key out-of-the-box functionality, including social sign-in, multi-factor authentication (MFA), forgotten password support, and infrastructure as code (AWS CloudFormation) support.
  • Ability to customize workflows: Amazon Cognito offers the option of a hosted UI where users can sign-in directly to Amazon Cognito or sign-in via social identity providers such as Amazon, Google, Apple, and Facebook. The Amazon Cognito hosted UI and workflows help save your team significant time and effort.
  • OIDC support: Amazon Cognito can securely pass user profile information to an existing authorization system following the ODIC authorization code flow. The authorization system uses the user profile information to secure access to the app.

Amazon Cognito overview

Amazon Cognito follows the OIDC specification to authenticate users of web and mobile apps. Users can sign in directly through the Amazon Cognito hosted UI or through a federated identity provider, such as Amazon, Facebook, Apple, or Google. The hosted UI workflows include sign-in and sign-up, password reset, and MFA. Since not all customer workflows are the same, you can customize Amazon Cognito workflows at key points with AWS Lambda functions, allowing you to run code without provisioning or managing servers. After a user authenticates, Amazon Cognito returns standard OIDC tokens. You can use the user profile information in the ID token to grant your users access to your own resources or you can use the tokens to grant access to APIs hosted by Amazon API Gateway. You can also exchange the tokens for temporary AWS credentials to access other AWS services.

Figure 1: Amazon Cognito sign-in flow

Figure 1: Amazon Cognito sign-in flow

OAuth 2.0 and OIDC

OAuth 2.0 is an open standard that allows a user to delegate access to their information to other websites or applications without handing over credentials. OIDC is an identity layer on top of OAuth 2.0 that uses OAuth 2.0 flows. OAuth 2.0 defines a number of flows to manage the interaction between the application, user, and authorization server. The right flow to use depends on the type of application.

The client credentials flow is used in machine-to-machine communications. You can use the client credentials flow to request an access token to access your own resources, which means you can use this flow when your app is requesting the token on its own behalf, not on behalf of a user. The authorization code grant flow is used to return an authorization code that is then exchanged for user pool tokens. Because the tokens are never exposed directly to the user, they are less likely to be shared broadly or accessed by an unauthorized party. However, a custom application is required on the back end to exchange the authorization code for user pool tokens. For security reasons, we recommend the Authorization Code Flow with Proof Key Code Exchange (PKCE) for public clients, such as single-page apps or native mobile apps.

The following table shows recommended flows per application type.

Application CFlow Description
Machine Client credentials Use this flow when your application is requesting the token on its own behalf, not on behalf of the user
Web app on a server Authorization code grant A regular web app on a web server
Single-page app Authorization code grant PKCE An app running in the browser, such as JavaScript
Mobile app Authorization code grant PKCE iOS or Android app

Securing the authorization code flow

Amazon Cognito can help you achieve compliance with regulatory frameworks and certifications, but it’s your responsibility to use the service in a way that remains compliant and secure. You need to determine the sensitivity of the user profile data in Amazon Cognito; adhere to your company’s security requirements, applicable laws and regulations; and configure your application and corresponding Amazon Cognito settings appropriately for your use case.

Note: You can learn more about regulatory frameworks and certifications at AWS Services in Scope by Compliance Program. You can download compliance reports from AWS Artifact.

We recommend that you use the authorization code flow with PKCE for single-page apps. Applications that use PKCE generate a random code verifier that’s created for every authorization request. Proof Key for Code Exchange by OAuth Public Clients has more information on use of a code verifier. In the following sections, I will show you how to set up the Amazon Cognito authorization endpoint for your app to support a code verifier.

The authorization code flow

In OpenID terms, the app is the relying party (RP) and Amazon Cognito is the OP. The flow for the authorization code flow with PKCE is as follows:

  1. The user enters the app home page URL in the browser and the browser fetches the app.
  2. The app generates the PKCE code challenge and redirects the request to the Amazon Cognito OAuth2 authorization endpoint (/oauth2/authorize).
  3. Amazon Cognito responds back to the user’s browser with the Amazon Cognito hosted sign-in page.
  4. The user signs in with their user name and password, signs up as a new user, or signs in with a federated sign-in. After a successful sign-in, Amazon Cognito returns the authorization code to the browser, which redirects the authorization code back to the app.
  5. The app sends a request to the Amazon Cognito OAuth2 token endpoint (/oauth2/token) with the authorization code, its client credentials, and the PKCE verifier.
  6. Amazon Cognito authenticates the app with the supplied credentials, validates the authorization code, validates the request with the code verifier, and returns the OpenID tokens, access token, ID token, and refresh token.
  7. The app validates the OpenID ID token and then uses the user profile information (claims) in the ID token to provide access to resources.(Optional) The app can use the access token to retrieve the user profile information from the Amazon Cognito user information endpoint (/userInfo).
  8. Amazon Cognito returns the user profile information (claims) about the authenticated user to the app. The app then uses the claims to provide access to resources.

The following diagram shows the authorization code flow with PKCE.

Figure 2: Authorization code flow

Figure 2: Authorization code flow

Implementing an app with Amazon Cognito authentication

Now that you’ve learned about Amazon Cognito OAuth implementation, let’s create a working example app that uses Amazon Cognito OAuth implementation. You’ll create an Amazon Cognito user pool along with an app client, the app, an Amazon Simple Storage Service (Amazon S3) bucket, and an Amazon CloudFront distribution for the app, and you’ll configure the app client.

Step 1. Create a user pool

Start by creating your user pool with the default configuration.

Create a user pool:

  1. Go to the Amazon Cognito console and select Manage User Pools. This takes you to the User Pools Directory.
  2. Select Create a user pool in the upper corner.
  3. Enter a Pool name, select Review defaults, and select Create pool.
  4. Copy the Pool ID, which will be used later to create your single-page app. It will be something like region_xxxxx. You will use it to replace the variable YOUR_USERPOOL_ID in a later step.(Optional) You can add additional features to the user pool, but this demonstration uses the default configuration. For more information see, the Amazon Cognito documentation.

The following figure shows you entering the user pool name.

Figure 3: Enter a name for the user pool

Figure 3: Enter a name for the user pool

The following figure shows the resulting user pool configuration.

Figure 4: Completed user pool configuration

Figure 4: Completed user pool configuration

Step 2. Create a domain name

The Amazon Cognito hosted UI lets you use your own domain name or you can add a prefix to the Amazon Cognito domain. This example uses an Amazon Cognito domain with a prefix.

Create a domain name:

  1. Sign in to the Amazon Cognito console, select Manage User Pools, and select your user pool.
  2. Under App integration, select Domain name.
  3. In the Amazon Cognito domain section, add your Domain prefix (for example, myblog).
  4. Select Check availability. If your domain isn’t available, change the domain prefix and try again.
  5. When your domain is confirmed as available, copy the Domain prefix to use when you create your single-page app. You will use it to replace the variable YOUR_COGNITO_DOMAIN_PREFIX in a later step.
  6. Choose Save changes.

The following figure shows creating an Amazon Cognito hosted domain.

Figure 5: Creating an Amazon Cognito hosted UI domain

Figure 5: Creating an Amazon Cognito hosted UI domain

Step 3. Create an app client

Now create the app client user pool. An app client is where you register your app with the user pool. Generally, you create an app client for each app platform. For example, you might create an app client for a single-page app and another app client for a mobile app. Each app client has its own ID, authentication flows, and permissions to access user attributes.

Create an app client:

  1. Sign in to the Amazon Cognito console, select Manage User Pools, and select your user pool.
  2. Under General settings, select App clients.
  3. Choose Add an app client.
  4. Enter a name for the app client in the App client name field.
  5. Uncheck Generate client secret and accept the remaining default configurations.

    Note: The client secret is used to authenticate the app client to the user pool. Generate client secret is unchecked because you don’t want to send the client secret on the URL using client-side JavaScript. The client secret is used by applications that have a server-side component that can secure the client secret.

  6. Choose Create app client as shown in the following figure.

    Figure 6: Create and configure an app client

    Figure 6: Create and configure an app client

  7. Copy the App client ID. You will use it to replace the variable YOUR_APPCLIENT_ID in a later step.

The following figure shows the App client ID which is automatically generated when the app client is created.

Figure 7: App client configuration

Figure 7: App client configuration

Step 4. Create an Amazon S3 website bucket

Amazon S3 is an object storage service that offers industry-leading scalability, data availability, security, and performance. We use Amazon S3 here to host a static website.

Create an Amazon S3 bucket with the following settings:

  1. Sign in to the AWS Management Console and open the Amazon S3 console.
  2. Choose Create bucket to start the Create bucket wizard.
  3. In Bucket name, enter a DNS-compliant name for your bucket. You will use this in a later step to replace the YOURS3BUCKETNAME variable.
  4. In Region, choose the AWS Region where you want the bucket to reside.

    Note: It’s recommended to create the Amazon S3 bucket in the same AWS Region as Amazon Cognito.

  5. Look up the region code from the region table (for example, US-East [N. Virginia] has a region code of us-east-1). You will use the region code to replace the variable YOUR_REGION in a later step.
  6. Choose Next.
  7. Select the Versioning checkbox.
  8. Choose Next.
  9. Choose Next.
  10. Choose Create bucket.
  11. Select the bucket you just created from the Amazon S3 bucket list.
  12. Select the Properties tab.
  13. Choose Static website hosting.
  14. Choose Use this bucket to host a website.
  15. For the index document, enter index.html and then choose Save.

Step 5. Create a CloudFront distribution

Amazon CloudFront is a fast content delivery network service that helps securely deliver data, videos, applications, and APIs to customers globally with low latency and high transfer speeds—all within a developer-friendly environment. In this step, we use CloudFront to set up an HTTPS-enabled domain for the static website hosted on Amazon S3.

Create a CloudFront distribution (web distribution) with the following modified default settings:

  1. Sign into the AWS Management Console and open the CloudFront console.
  2. Choose Create Distribution.
  3. On the first page of the Create Distribution Wizard, in the Web section, choose Get Started.
  4. Choose the Origin Domain Name from the dropdown list. It will be YOURS3BUCKETNAME.s3.amazonaws.com.
  5. For Restrict Bucket Access, select Yes.
  6. For Origin Access Identity, select Create a New Identity.
  7. For Grant Read Permission on Bucket, select Yes, Update Bucket Policy.
  8. For the Viewer Protocol Policy, select Redirect HTTP to HTTPS.
  9. For Cache Policy, select Managed-Caching Disabled.
  10. Set the Default Root Object to index.html.(Optional) Add a comment. Comments are a good place to describe the purpose of your distribution, for example, “Amazon Cognito SPA.”
  11. Select Create Distribution. The distribution will take a few minutes to create and update.
  12. Copy the Domain Name. This is the CloudFront distribution domain name, which you will use in a later step as the DOMAINNAME value in the YOUR_REDIRECT_URI variable.

Step 6. Create the app

Now that you’ve created the Amazon S3 bucket for static website hosting and the CloudFront distribution for the site, you’re ready to use the code that follows to create a sample app.

Use the following information from the previous steps:

  1. YOUR_COGNITO_DOMAIN_PREFIX is from Step 2.
  2. YOUR_REGION is the AWS region you used in Step 4 when you created your Amazon S3 bucket.
  3. YOUR_APPCLIENT_ID is the App client ID from Step 3.
  4. YOUR_USERPOOL_ID is the Pool ID from Step 1.
  5. YOUR_REDIRECT_URI, which is https://DOMAINNAME/index.html, where DOMAINNAME is your domain name from Step 5.

Create userprofile.js

Use the following text to create the userprofile.js file. Substitute the preceding pre-existing values for the variables in the text.

var myHeaders = new Headers();
myHeaders.set('Cache-Control', 'no-store');
var urlParams = new URLSearchParams(window.location.search);
var tokens;
var domain = "YOUR_COGNITO_DOMAIN_PREFIX";
var region = "YOUR_REGION";
var appClientId = "YOUR_APPCLIENT_ID";
var userPoolId = "YOUR_USERPOOL_ID";
var redirectURI = "YOUR_REDIRECT_URI";

//Convert Payload from Base64-URL to JSON
const decodePayload = payload => {
  const cleanedPayload = payload.replace(/-/g, '+').replace(/_/g, '/');
  const decodedPayload = atob(cleanedPayload)
  const uriEncodedPayload = Array.from(decodedPayload).reduce((acc, char) => {
    const uriEncodedChar = ('00' + char.charCodeAt(0).toString(16)).slice(-2)
    return `${acc}%${uriEncodedChar}`
  }, '')
  const jsonPayload = decodeURIComponent(uriEncodedPayload);

  return JSON.parse(jsonPayload)
}

//Parse JWT Payload
const parseJWTPayload = token => {
    const [header, payload, signature] = token.split('.');
    const jsonPayload = decodePayload(payload)

    return jsonPayload
};

//Parse JWT Header
const parseJWTHeader = token => {
    const [header, payload, signature] = token.split('.');
    const jsonHeader = decodePayload(header)

    return jsonHeader
};

//Generate a Random String
const getRandomString = () => {
    const randomItems = new Uint32Array(28);
    crypto.getRandomValues(randomItems);
    const binaryStringItems = randomItems.map(dec => `0${dec.toString(16).substr(-2)}`)
    return binaryStringItems.reduce((acc, item) => `${acc}${item}`, '');
}

//Encrypt a String with SHA256
const encryptStringWithSHA256 = async str => {
    const PROTOCOL = 'SHA-256'
    const textEncoder = new TextEncoder();
    const encodedData = textEncoder.encode(str);
    return crypto.subtle.digest(PROTOCOL, encodedData);
}

//Convert Hash to Base64-URL
const hashToBase64url = arrayBuffer => {
    const items = new Uint8Array(arrayBuffer)
    const stringifiedArrayHash = items.reduce((acc, i) => `${acc}${String.fromCharCode(i)}`, '')
    const decodedHash = btoa(stringifiedArrayHash)

    const base64URL = decodedHash.replace(/\+/g, '-').replace(/\//g, '_').replace(/=+$/, '');
    return base64URL
}

// Main Function
async function main() {
  var code = urlParams.get('code');

  //If code not present then request code else request tokens
  if (code == null){

    // Create random "state"
    var state = getRandomString();
    sessionStorage.setItem("pkce_state", state);

    // Create PKCE code verifier
    var code_verifier = getRandomString();
    sessionStorage.setItem("code_verifier", code_verifier);

    // Create code challenge
    var arrayHash = await encryptStringWithSHA256(code_verifier);
    var code_challenge = hashToBase64url(arrayHash);
    sessionStorage.setItem("code_challenge", code_challenge)

    // Redirtect user-agent to /authorize endpoint
    location.href = "https://"+domain+".auth."+region+".amazoncognito.com/oauth2/authorize?response_type=code&state="+state+"&client_id="+appClientId+"&redirect_uri="+redirectURI+"&scope=openid&code_challenge_method=S256&code_challenge="+code_challenge;
  } else {

    // Verify state matches
    state = urlParams.get('state');
    if(sessionStorage.getItem("pkce_state") != state) {
        alert("Invalid state");
    } else {

    // Fetch OAuth2 tokens from Cognito
    code_verifier = sessionStorage.getItem('code_verifier');
  await fetch("https://"+domain+".auth."+region+".amazoncognito.com/oauth2/token?grant_type=authorization_code&client_id="+appClientId+"&code_verifier="+code_verifier+"&redirect_uri="+redirectURI+"&code="+ code,{
  method: 'post',
  headers: {
    'Content-Type': 'application/x-www-form-urlencoded'
  }})
  .then((response) => {
    return response.json();
  })
  .then((data) => {

    // Verify id_token
    tokens=data;
    var idVerified = verifyToken (tokens.id_token);
    Promise.resolve(idVerified).then(function(value) {
      if (value.localeCompare("verified")){
        alert("Invalid ID Token - "+ value);
        return;
      }
      });
    // Display tokens
    document.getElementById("id_token").innerHTML = JSON.stringify(parseJWTPayload(tokens.id_token),null,'\t');
    document.getElementById("access_token").innerHTML = JSON.stringify(parseJWTPayload(tokens.access_token),null,'\t');
  });

    // Fetch from /user_info
    await fetch("https://"+domain+".auth."+region+".amazoncognito.com/oauth2/userInfo",{
      method: 'post',
      headers: {
        'authorization': 'Bearer ' + tokens.access_token
    }})
    .then((response) => {
      return response.json();
    })
    .then((data) => {
      // Display user information
      document.getElementById("userInfo").innerHTML = JSON.stringify(data, null,'\t');
    });
  }}}
  main();

Create the verifier.js file

Use the following text to create the verifier.js file.

var key_id;
var keys;
var key_index;

//verify token
async function verifyToken (token) {
//get Cognito keys
keys_url = 'https://cognito-idp.'+ region +'.amazonaws.com/' + userPoolId + '/.well-known/jwks.json';
await fetch(keys_url)
.then((response) => {
return response.json();
})
.then((data) => {
keys = data['keys'];
});

//Get the kid (key id)
var tokenHeader = parseJWTHeader(token);
key_id = tokenHeader.kid;

//search for the kid key id in the Cognito Keys
const key = keys.find(key =>key.kid===key_id)
if (key === undefined){
return "Public key not found in Cognito jwks.json";
}

//verify JWT Signature
var keyObj = KEYUTIL.getKey(key);
var isValid = KJUR.jws.JWS.verifyJWT(token, keyObj, {alg: ["RS256"]});
if (isValid){
} else {
return("Signature verification failed");
}

//verify token has not expired
var tokenPayload = parseJWTPayload(token);
if (Date.now() >= tokenPayload.exp * 1000) {
return("Token expired");
}

//verify app_client_id
var n = tokenPayload.aud.localeCompare(appClientId)
if (n != 0){
return("Token was not issued for this audience");
}
return("verified");
};

Create an index.html file

Use the following text to create the index.html file.

<!doctype html>

<html lang="en">
<head>
<meta charset="utf-8">

<title>MyApp</title>
<meta name="description" content="My Application">
<meta name="author" content="Your Name">
</head>

<body>
<h2>Cognito User</h2>

<p style="white-space:pre-line;" id="token_status"></p>

<p>Id Token</p>
<p style="white-space:pre-line;" id="id_token"></p>

<p>Access Token</p>
<p style="white-space:pre-line;" id="access_token"></p>

<p>User Profile</p>
<p style="white-space:pre-line;" id="userInfo"></p>
<script language="JavaScript" type="text/javascript"
src="https://kjur.github.io/jsrsasign/jsrsasign-latest-all-min.js">
</script>
<script src="js/verifier.js"></script>
<script src="js/userprofile.js"></script>
</body>
</html>

Upload the files into the Amazon S3 Bucket you created earlier

Upload the files you just created to the Amazon S3 bucket that you created in Step 4. If you’re using Chrome or Firefox browsers, you can choose the folders and files to upload and then drag and drop them into the destination bucket. Dragging and dropping is the only way that you can upload folders.

  1. Sign in to the AWS Management Console and open the Amazon S3 console.
  2. In the Bucket name list, choose the name of the bucket that you created earlier in Step 4.
  3. In a window other than the console window, select the index.html file to upload. Then drag and drop the file into the console window that lists the destination bucket.
  4. In the Upload dialog box, choose Upload.
  5. Choose Create Folder.
  6. Enter the name js and choose Save.
  7. Choose the js folder.
  8. In a window other than the console window, select the userprofile.js and verifier.js files to upload. Then drag and drop the files into the console window js folder.

    Note: The Amazon S3 bucket root will contain the index.html file and a js folder. The js folder will contain the userprofile.js and verifier.js files.

Step 7. Configure the app client settings

Use the Amazon Cognito console to configure the app client settings, including identity providers, OAuth flows, and OAuth scopes.

Configure the app client settings:

  1. Go to the Amazon Cognito console.
  2. Choose Manage your User Pools.
  3. Select your user pool.
  4. Select App integration, and then select App client settings.
  5. Under Enabled Identity Providers, select Cognito User Pool.(Optional) You can add federated identity providers. Adding User Pool Sign-in Through a Third-Party has more information about how to add federation providers.
  6. Enter the Callback URL(s) where the user is to be redirected after successfully signing in. The callback URL is the URL of your web app that will receive the authorization code. In our example, this will be the Domain Name for the CloudFront distribution you created earlier. It will look something like https://DOMAINNAME/index.html where DOMAINNAME is xxxxxxx.cloudfront.net.

    Note: HTTPS is required for the Callback URLs. For this example, I used CloudFront as a HTTPS endpoint for the app in Amazon S3.

  7. Next, select Authorization code grant from the Allowed OAuth Flows and OpenID from Allowed OAuth Scopes. The OpenID scope will return the ID token and grant access to all user attributes that are readable by the client.
  8. Choose Save changes.

Step 8. Show the app home page

Now that the Amazon Cognito user pool is configured and the sample app is built, you can test using Amazon Cognito as an OP from the sample JavaScript app you created in Step 6.

View the app’s home page:

  1. Open a web browser and enter the app’s home page URL using the CloudFront distribution to serve your index.html page created in Step 6 (https://DOMAINNAME/index.html) and the app will redirect the browser to the Amazon Cognito /authorize endpoint.
  2. The /authorize endpoint redirects the browser to the Amazon Cognito hosted UI, where the user can sign in or sign up. The following figure shows the user sign-in page.

    Figure 8: User sign-in page

    Figure 8: User sign-in page

Step 9. Create a user

You can use the Amazon Cognito user pool to manage your users or you can use a federated identity provider. Users can sign in or sign up from the Amazon Cognito hosted UI or from a federated identity provider. If you configured a federated identity provider, users will see a list of federated providers that they can choose from. When a user chooses a federated identity provider, they are redirected to the federated identity provider sign-in page. After signing in, the browser is directed back to Amazon Cognito. For this post, Amazon Cognito is the only identity provider, so you will use the Amazon Cognito hosted UI to create an Amazon Cognito user.

Create a new user using Amazon Cognito hosted UI:

  1. Create a new user by selecting Sign up and entering a username, password, and email address. Then select the Sign up button. The following figure shows the sign up screen.

    Figure 9: Sign up with a new account

    Figure 9: Sign up with a new account

  2. The Amazon Cognito sign up workflow will verify the email address by sending a verification code to that address. The following figure shows the prompt to enter the verification code.

    Figure 10: Enter the verification code

    Figure 10: Enter the verification code

  3. Enter the code from the verification email in the Verification Code text box.
  4. Select Confirm Account.

Step 10. Viewing the Amazon Cognito tokens and profile information

After authentication, the app displays the tokens and user information. The following figure shows the OAuth2 access token and OIDC ID token that are returned from the /token endpoint and the user profile returned from the /userInfo endpoint. Now that the user has been authenticated, the application can use the user’s email address to look up the user’s account information in an application data store. Based on the user’s account information, the application can grant/restrict access to paid content or show account information like order history.

Figure 11: Token and user profile information

Figure 11: Token and user profile information

Note: Many browsers will cache redirects. If your browser is repeatedly redirecting to the index.html page, clear the browser cache.

Summary

In this post, we’ve shown you how easy it is to add user authentication to your web and mobile apps with Amazon Cognito.

We created a Cognito User Pool as our user directory, assigned a domain name to the Amazon Cognito hosted UI, and created an application client for our application. Then we created an Amazon S3 bucket to host our website. Next, we created a CloudFront distribution for our Amazon S3 bucket. Then we created our application and uploaded it to our Amazon S3 website bucket. From there, we configured the client app settings with our identity provider, OAuth flows, and scopes. Then we accessed our application and used the Amazon Cognito sign-in flow to create a username and password. Finally, we logged into our application to see the OAuth and OIDC tokens.

Amazon Cognito saves you time and effort when implementing authentication with an intuitive UI, OAuth2 and OIDC support, and customizable workflows. You can now focus on building features that are important to your core business.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon Cognito forum or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
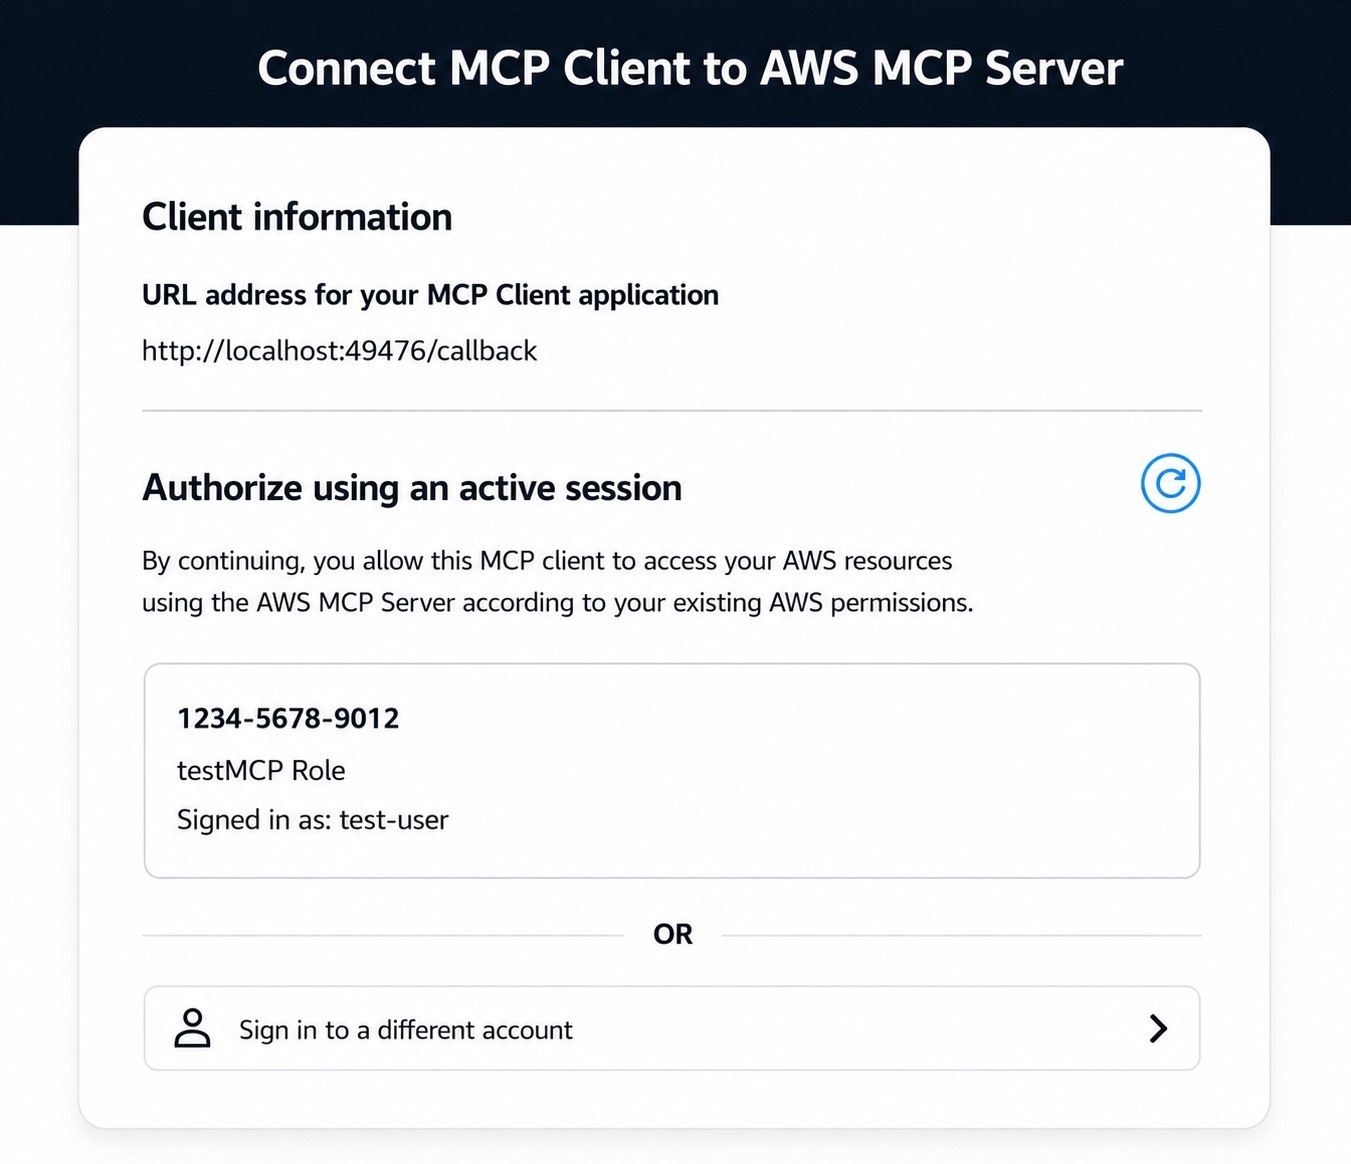
Author

George Conti

George is a Solution Architect for the AWS Financial Services team. He is passonate about technology and helping Financial Services Companies build solutions with AWS Services.