Centralized dashboard for monitoring SES identities

Post Syndicated from Manoj Gaddam original https://aws.amazon.com/blogs/messaging-and-targeting/centralized-dashboard-for-monitoring-ses-identities/

Organizations running Amazon Simple Email Service (Amazon SES) across multiple AWS accounts face a common challenge: visibility. When you have dozens or hundreds of accounts sending email, answering basic questions becomes surprisingly difficult:

  • How many SES identities exist across my organization?
  • Which identities are verified and pending?
  • Are there stale or unused identities that should be cleaned up?
  • Which accounts are sending from which domains?
  • Is DKIM properly configured for all sending domains?

Without centralized visibility, security teams can’t audit email-sending capabilities, compliance teams can’t enforce domain policies, and operations teams discover rogue identities only after deliverability issues arise.

This post presents two solutions for building a centralized SES identity dashboard across your AWS Organization. Each collects identity data from all member accounts and presents it through Amazon Athena and Amazon Quick Sight.

  • Option 1: A single AWS Lambda function that scans all accounts sequentially, best for organizations with fewer than 50 accounts.
  • Option 2: An AWS Step Functions state machine with a Map state for parallel execution, best for organizations with 50 or more accounts.

Both solutions provide centralized visibility into your SES posture with minimal member account footprint. You can deploy the option that best suits your needs by following the guidance in this post.

Solution architecture

The following diagram shows the end-to-end scan workflow, from the scheduled trigger through cross-account collection to the Amazon Athena and Amazon Quick Sight presentation layer.
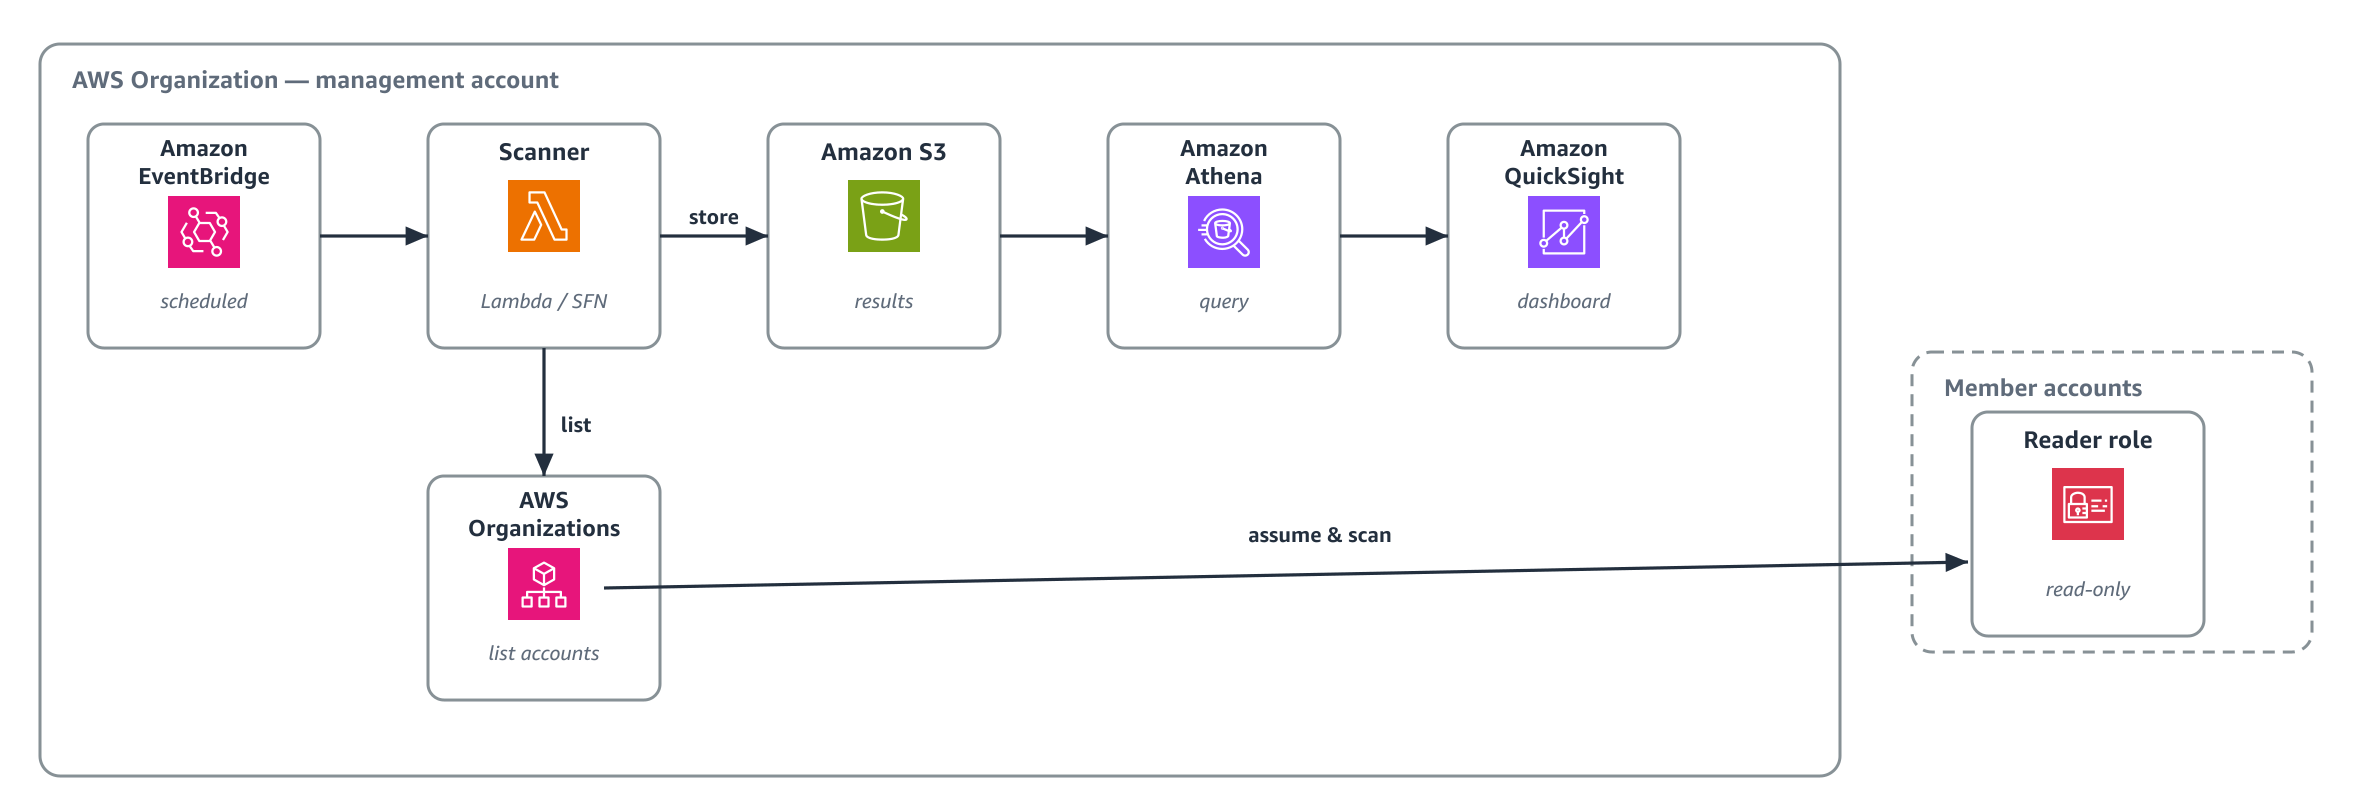
SES identity scan workflow from the scheduled trigger through cross-account collection to Athena and Amazon Quick Sight

Figure 1: End-to-end SES identity scan workflow from the scheduled trigger through cross-account collection to the Athena and Amazon Quick Sight presentation layer

For each identity, the scan collects the attributes Amazon SES reports for that identity: identity name, type (domain or email), verification status, DKIM configuration (signing enabled, status, and current key length), the custom MAIL FROM domain and its status, and whether sending is enabled.

SPF and DMARC are published as DNS records by the domain owner rather than reported by Amazon SES, so they make a natural next layer to add on top of this scan.

Option 1: Single Lambda (fewer than 50 accounts)

A single AWS Lambda function handles the entire scan sequentially, at approximately 30 seconds per account. Because a sequential scan of 50 or more accounts exceeds what one invocation can complete, Option 2 parallelizes the work across accounts.
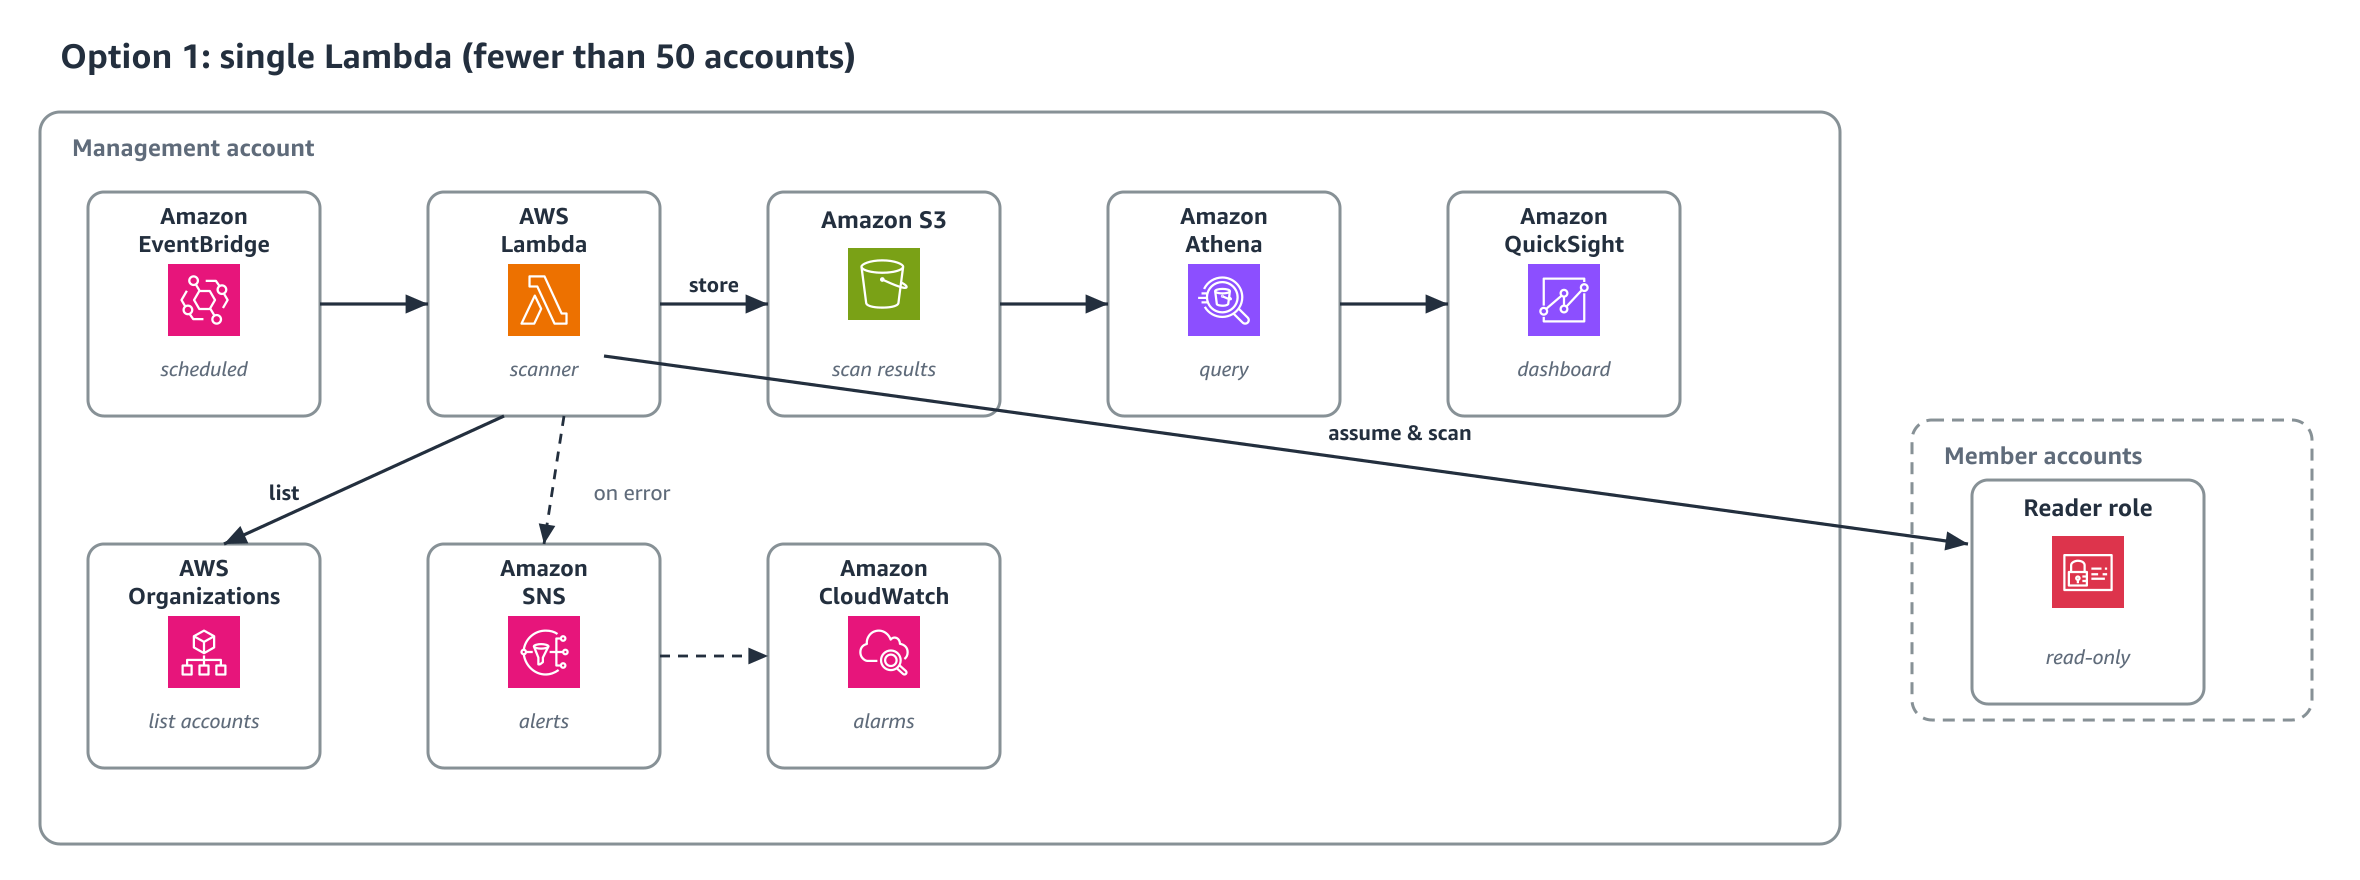
Option 1 architecture using a single Lambda function to scan accounts sequentially

Figure 2: Option 1 architecture using a single Lambda function to scan accounts sequentially

How Option 1 works

  • Amazon EventBridge triggers the scanner Lambda on a daily schedule (configurable).
  • The Lambda calls organizations:ListAccounts to discover all active member accounts.
  • For each account, it calls sts:AssumeRole to assume the SES-Identity-Reader role. The role’s trust policy requires three conditions: the scanner role’s aws:PrincipalArn, your aws:PrincipalOrgID, and a per-deployment external ID passed as a NoEcho parameter. Generate a unique value for this deployment, and don’t reuse a fixed one.
  • Using the assumed credentials, it calls ec2:DescribeRegions to discover enabled Regions, then ses:ListEmailIdentities and ses:GetEmailIdentity in each Region.
  • Results are written to Amazon S3 as JSON Lines, both a timestamped historical path and a latest/ path for Athena.
  • If any accounts or Regions fail, the Lambda records the failures in scans/summary/latest.json and publishes an error summary to Amazon Simple Notification Service (Amazon SNS). If accounts exist but zero identities are collected, the run fails without overwriting scans/latest (the previous good scan is preserved) so the SES-Scanner-Errors alarm fires.
  • Amazon CloudWatch alarm (a missed-run alarm) fires if no successful scan occurs within 25 hours. Additional alarms cover Lambda Errors and dead-letter-queue depth.

Deploying Option 1 in your AWS account

Prerequisites for Option 1:

  • AWS account access with permissions to deploy CloudFormation stacks and StackSets.
  • Your AWS Organization ID (format: o-xxxxxxxxxx).
  • Your management account ID (12 digits).
  • From the repository, you need the ses-reader-role.yaml and ses-scanner-stack.yaml files found in /option-1/.

Step 1: Deploy the cross-account IAM role

Template: option-1-ses-reader-role.yaml

  • Enable trusted access between CloudFormation StackSets and AWS Organizations. This is a one-time prerequisite for service-managed StackSets and is a no-op if already enabled.
  • In the CloudFormation console, this is offered automatically the first time you create a service-managed StackSet. Alternatively, run the following command from the management account: aws organizations enable-aws-service-access --service-principal member.org.stacksets.amazonaws.com
  • Open the AWS CloudFormation console in your management account.
  • Navigate to StackSets and choose Create StackSet.
  • Upload the ses-reader-role.yaml file.
  • Configure the parameters:
    • ManagementAccountId : Your 12-digit management account ID.
    • OrganizationId : Your organization ID (o-xxxxxxxxxx). Restricts assumption to principals in your organization.
    • ExternalId : A unique random secret you generate for this deployment (8–128 chars). Supply the same value to the scanner stack in Step 2. Don’t reuse the sample value.
    • ScannerRoleName : Leave default (SES-Identity-Scanner-Role) unless you renamed the scanner role.
  • Choose Service-managed permissions.
  • Enable Auto-deployment (so new accounts automatically receive the role).
  • Deploy to your organization root (r-xxxx) in a single Region (IAM roles are global).
  • Wait for the operation to show SUCCEEDED for all member accounts.

This deploys a strictly read-only IAM role (SES-Identity-Reader) to all member accounts. The role grants only the SES v2 read actions it uses (ses:ListEmailIdentities, ses:GetEmailIdentity) plus ec2:DescribeRegions, and no write or other permissions.

Step 2: Deploy the scanner stack

Template: option-1-ses-scanner-stack.yaml

  • Open the AWS CloudFormation console in your management account.
  • Choose Create stack, then With new resources (standard).
  • Upload the ses-scanner-stack.yaml file.
  • Configure the parameters:
    • ScheduleExpression : Scan frequency (default: rate(1 day)).
    • OrganizationId : Your organization ID (o-xxxxxxxxxx). Scopes cross-account sts:AssumeRole through an aws:ResourceOrgID condition.
    • ExternalId : The same value you generated in Step 1.
    • AlertEmail : Email address that receives scan-error summaries and CloudWatch alarms.
  • Acknowledge IAM resource creation and choose Submit.
  • Wait for CREATE_COMPLETE.
  • After the stack is created, confirm the SNS subscription in the email sent to AlertEmail. Until you confirm, error notifications and alarms are not delivered.

The stack creates:

  • Two S3 buckets (a scan-results bucket and an access-logs bucket, both versioned, public access blocked, with lifecycle rules including noncurrent-version expiration).
  • A Lambda function (Python 3.12, 512 MB, 15-minute timeout) with an explicit CloudWatch log group (90-day retention).
  • An Amazon EventBridge rule, an SQS dead-letter queue.
  • CloudWatch alarms (missed run, Lambda Errors, DLQ depth).
  • An SNS topic with an email subscription.
  • An enforced encrypted Athena workgroup.
  • An AWS Glue database with table definition for Athena.

Note on data retention: Timestamped historical scans are written under scans/archive/, and both lifecycle rules (expiration and transition to Infrequent Access) are scoped to that prefix. Three pointers are continuously overwritten: scans/latest/, scans/summary/, and athena-results/. These are deliberately excluded from expiration, so the most recent good scan is always preserved, including when a run fails closed.

Step 3: Test the scanner

  • Open the AWS Lambda console.
  • Select the SES-Identity-Scanner-v2 function.
  • Choose Test, create a test event with payload {}, and choose Test.
  • Review the execution result, which should show accounts scanned, total identities found, and any errors.
  • Verify the JSON Lines file exists in your S3 bucket under scans/latest/.

Step 4: Query with Amazon Athena

  • Open the Amazon Athena console.
  • Select the workgroup the stack creates (<stack-name>-ses-identity). It enforces an encrypted results location inside the hardened scan-results bucket, so you do not set a query result location manually.
  • Select the ses_identity_dashboard database.
  • Run the following queries to explore your organization’s SES posture.

Organization summary:

SELECT account_id,
       COUNT(*) as total_identities,
       SUM(CASE WHEN verified THEN 1 ELSE 0 END) as verified_count,
       SUM(CASE WHEN dkim_status = 'SUCCESS' THEN 1 ELSE 0 END) as dkim_configured
FROM ses_identities
GROUP BY account_id
ORDER BY total_identities DESC;

Identities requiring action:

SELECT account_id, region, identity_name, identity_type, dkim_status
FROM ses_identities
WHERE verified = false
   OR (identity_type = 'DOMAIN' AND dkim_status != 'SUCCESS')
ORDER BY account_id;

More queries: option-1-sample-athena-queries.sql

Step 5: Visualize with Amazon Quick Sight

  • Open the Amazon Quick Sight console.
  • Create a new dataset using Amazon Athena as the data source.
  • Select the ses_identities table from the ses_identity_dashboard database.
  • Import the data into SPICE for fast dashboard performance.
  • Create visualizations: bar chart (identities by account), pie chart (verified and unverified), heat map (identities by Region and account), and a detail table with filters.
  • Schedule SPICE refresh to run after the daily scan completes.
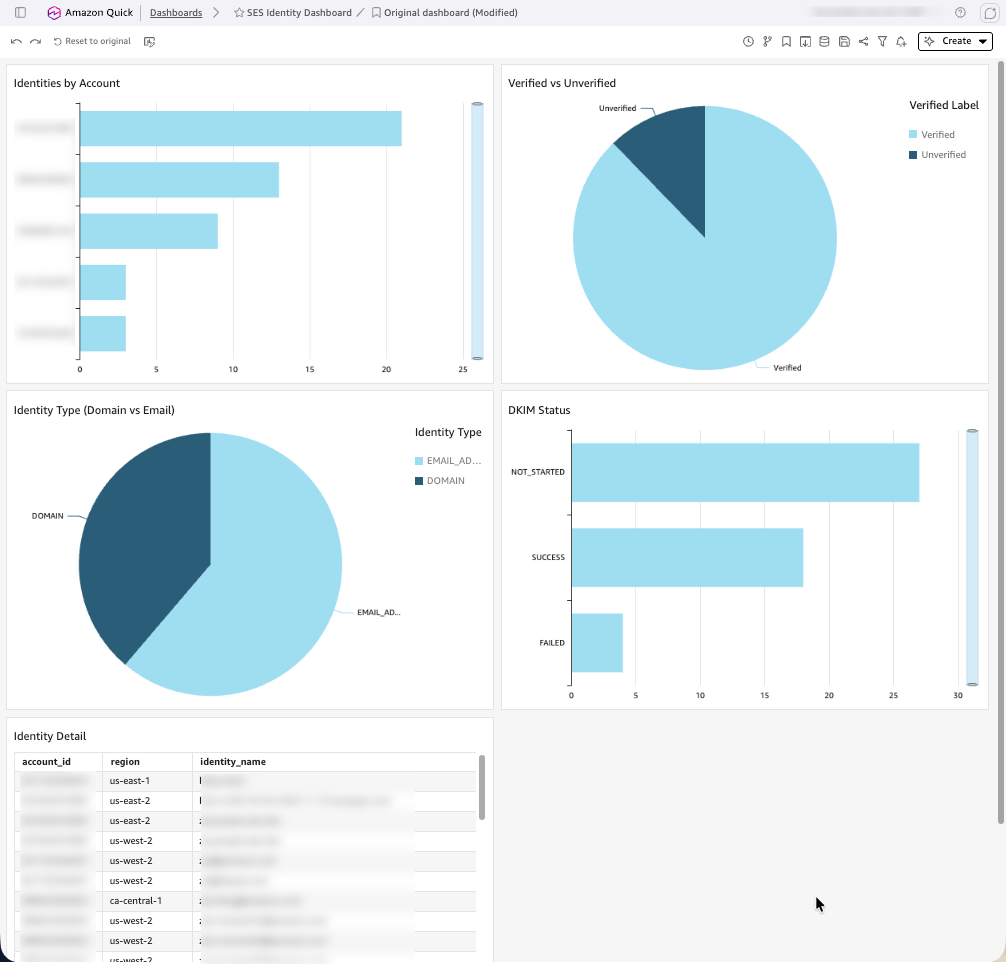
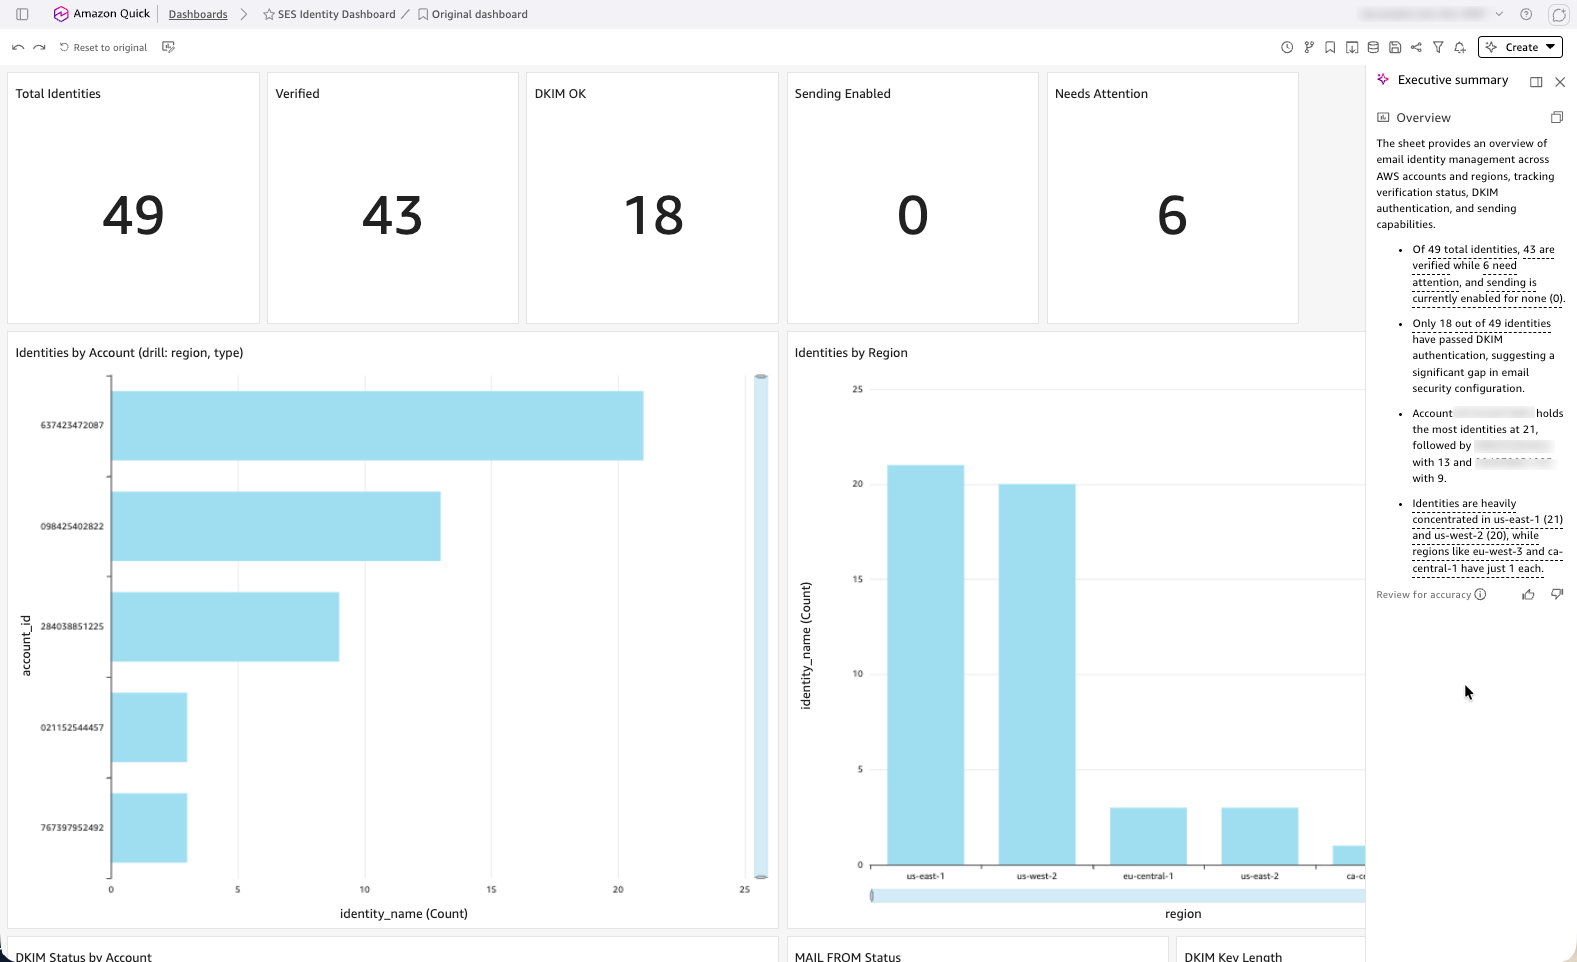
Amazon Quick Sight dashboard showing SES identities by account and verification status Amazon Quick Sight dashboard showing SES identities by Region with a detail table

Option 2: Step Functions with parallel account scanning (50+ accounts)

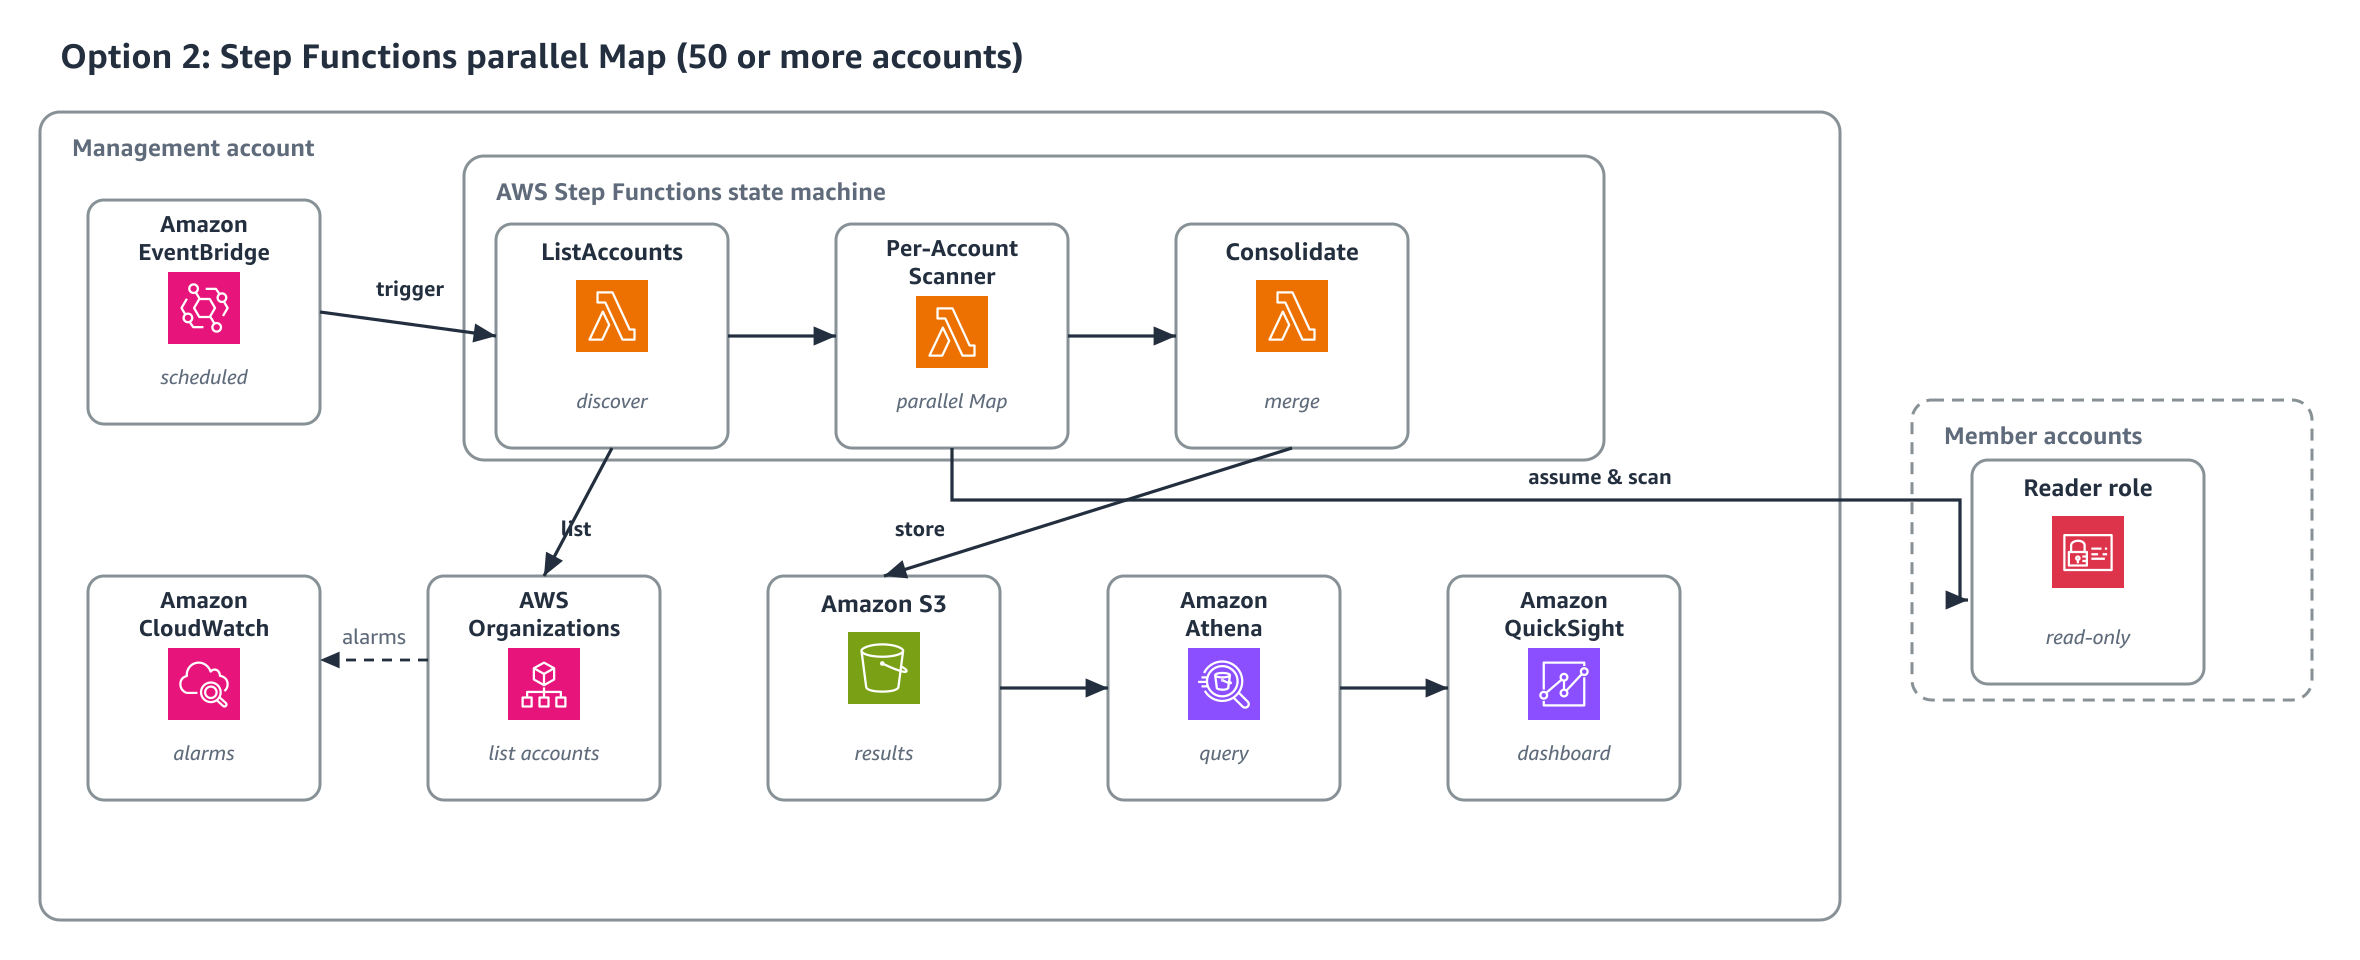
AWS Step Functions with a Map state provides parallel execution. With up to 40 concurrent per-account scans, an estimated 280 accounts complete in roughly 3–5 minutes, with built-in retry logic and per-account error isolation. The template uses an inline Map, which caps concurrency at 40. To scale beyond 40, switch the ItemProcessor mode to DISTRIBUTED. This additionally requires three actions on the state machine plus S3 ItemReader/ResultWriter permissions.

  • states:StartExecution
  • states:DescribeExecution
  • states:StopExecution
Option 2 architecture using a Step Functions state machine with a Map state for parallel account scanning

Figure 3: Option 2 architecture using a Step Functions state machine with a Map state for parallel account scanning

Prerequisites for Option 2:

  • AWS Organizations enabled with a management account (or delegated administrator).
  • Permissions to deploy CloudFormation StackSets across member accounts.
  • Amazon SES configured in one or more member accounts (identities to scan).
  • Console access to AWS CloudFormation, AWS Lambda, Amazon S3, and Amazon Athena.
  • Clone the repository:
git clone https://github.com/aws-samples/sample-SES-Identity-Dashboard.git

How Option 2 works

Refer to Option 2 image for the workflow:

  • Amazon EventBridge triggers the Step Functions state machine on schedule.
  • The ListAccounts Lambda discovers all active organization accounts and returns them as a JSON array.
  • The Map state iterates over the accounts array with MaxConcurrency: 40 (inline Map. Do not raise above 40 without switching to a Distributed Map).
  • Each Per-Account Scanner Lambda receives a single account ID, assumes the reader role, scans all enabled Regions, and writes per-account results to S3. Per-region and per-identity failures are reported in-band rather than silently dropped.
  • The Consolidate Lambda merges all per-account files into a single JSON Lines file at the scans/latest/ path. It also writes latest.json and fails the execution only when zero identities were collected and at least one account, Region, or identity failed. A legitimately empty organization (every account scanned cleanly with no identities) is treated as healthy, and the previous scans/latest/ is preserved when the run fails closed.
  • On any account failure, Step Functions automatically retries (two attempts, 60-second interval, backoff rate 2.0).
  • Failed accounts are captured in the execution output without stopping the scan for other accounts.

The Map state processes up to 40 accounts concurrently. Each per-account Lambda completes in approximately 30 seconds, so 280 accounts finish in 3–5 minutes. State machine logging and AWS X-Ray tracing are enabled. A SES-Scanner-SFN-Execution-Failed alarm covers failed executions. The Step Functions console provides a visual execution history showing exactly which accounts succeeded or failed.

Deploying Option 2 in your AWS account

Template: option-2-ses-scanner-stepfunctions.yaml

  • Confirm the SES-Identity-Reader role is already deployed to all member accounts (Step 1 from Option 1).
  • Open the AWS CloudFormation console in your management account.
  • Upload the ses-scanner-stepfunctions.yaml file.
  • Configure the parameters:
    • OrganizationId : Your organization ID (o-xxxxxxxxxx). Scopes sts:AssumeRole through aws:ResourceOrgID.
    • ExternalId : The same per-deployment secret used by the reader role.
    • AlertEmail : Address subscribed to the alert SNS topic (confirm the subscription email).
    • ScheduleExpression.
    • and optionally MaxConcurrency (default 40. Bounded 1–40 for the inline Map).
  • Acknowledge IAM resource creation and choose Submit.
  • Wait for CREATE_COMPLETE.
  • The Athena table schema, sample queries, and Amazon Quick Sight dashboard configuration are the same as Option 1. Only the AWS Glue database name differs. Option 2 creates ses_identity_dashboard_sfn, while Option 1 uses ses_identity_dashboard. Point your Athena queries and Amazon Quick Sight dataset at ses_identity_dashboard_sfn. Query results are written to the enforced encrypted workgroup <stack-name>-ses-identity-sfn. Select it in the Athena console. The distinct names let both options run in the same account.

Clean up

To remove all resources created by this solution:

  • Delete the scanner CloudFormation stack from your management account.
  • In StackSets, delete all stack instances, then delete the StackSet itself.
  • If you created test SES identities, delete them from the SES console in each account.
  • Empty and delete the S3 bucket if it was not removed by the stack deletion (buckets with objects require manual emptying).

Conclusion

This solution gives your organization a single, centralized view of SES identities across all accounts, deployed in minutes with minimal member account footprint.

Start with Option 1 for immediate value. When your organization grows beyond 50 accounts, deploy Option 2. The data format, Athena queries, and Amazon Quick Sight dashboards remain unchanged. Only the orchestration layer changes.

To get started, clone the repository and deploy Option 1. For more information, see Amazon SES v2 API reference and Amazon Quick Sight User Guide.

About the authors

Manoj Gaddam

Manoj Gaddam

Manoj is a Technical Account Manager at AWS, where he helps enterprise customers architect, operate, and optimize their cloud solutions. He partners with strategic software and technology customers to help them achieve their business and technical goals on AWS. His focus spans analytics, storage, security, and modern compute and container workloads, as well as helping customers explore and adopt AI and generative AI capabilities on AWS. Outside of work, he enjoys traveling and spending time with friends.

Ajinkya Bhoite

Ajinkya Bhoite

Ajinkya is a Senior Cloud Support Engineer at AWS and a Subject Matter Expert in Amazon Simple Email Service (SES) and Amazon S3, where he helps customers untangle their trickiest SES and S3 problems. Away from the cloud, he’s a reader, a runner, and a published novelist, author of the Kindle fiction Shiva Stone: Hampi’s Hidden Treasure.

Mrinal Sorte

Mrinal Sorte

Mrinal is a Technical Account Manager at AWS, where she helps enterprise customers build secure, resilient, and compliant workloads on AWS. Passionate about AI, automation, and security, she actively contributes to AWS technical communities and enjoys sharing knowledge through workshops and enablement sessions. She works backwards from customer objectives to design and implement scalable solutions that drive innovation, reduce risk, and accelerate growth.

Sassan Hajrasooliha

Sassan Hajrasooliha

Sassan is a Senior Specialist AWS Solutions Architect with AWS. He has been working as an IT professional since 2003 and covers diverse technologies from different vendors in the industry. Throughout his career he has helped customers ranging from startups to multinational enterprises and public agencies get the best out of their IT systems for their businesses and missions. At AWS he is focused on Communication Developer Services like SES and EUM, as well as infrastructure migration and modernization.

Automate medical coding with Step Functions and Amazon Bedrock AgentCore

Post Syndicated from Sachin Doshi original https://aws.amazon.com/blogs/architecture/automate-medical-coding-with-step-functions-and-amazon-bedrock-agentcore/

With AI agents, you can automate medical coding while keeping the workflow deterministic, auditable, and subject to human approval. The key is division of labor: the workflow engine owns sequencing and approval gates, while agents reason within individual, bounded steps. Handing the entire workflow to an agent would make the runtime path a property of the model’s reasoning, which is difficult to review and replay.

Medical coding makes this concrete. Teams must translate free-text clinical terms like “migrane” (a typo) or “flutters in my chest sometimes” into standardized codes before they can analyze or report the data. The target vocabularies include controlled medical dictionaries such as MedDRA for adverse events and WHODrug for medications. This work is safety-critical because a coding error can send an adverse event to the wrong safety signal. Yet it’s mostly repetitive work, with skilled coders reviewing terms one by one. The opportunity is to code the confident cases automatically and route only the ambiguous ones to a human.

In this post, we show you how to combine deterministic orchestration with bounded agentic reasoning using AWS Step Functions and the Amazon Bedrock AgentCore harness integration, a managed capability of Amazon Bedrock AgentCore. We walk through a medical coding workflow that escalates cheapest-first: a safety block-list, then exact matching, then an AI agent only for the terms that need judgment. We also explain the design decisions that keep the model bounded. The complete sample, including infrastructure code and a seeded test dataset, is available in the aws-samples GitHub repository.

Note that MedDRA is a registered trademark of the International Federation of Pharmaceutical Manufacturers and Associations (IFPMA), managed by the MedDRA Maintenance and Support Services Organization (MSSO). WHODrug is maintained by the Uppsala Monitoring Centre (UMC). Both are proprietary, licensed dictionaries. Deploying against them requires a valid subscription. The sample dataset contains generated study identifiers and verbatims with a de minimis illustrative set of dictionary entries, and no patient data. The AWS services used in this sample, including Amazon Aurora and Amazon Bedrock, are HIPAA-eligible when used under a signed AWS Business Associate Addendum (BAA). Before processing protected health information, see the HIPAA Eligible Services Reference and the AWS HIPAA Compliance overview.

Solution overview

The design follows one principle: spend the cheapest, most deterministic mechanism that can code a term with confidence and escalate only when it can’t. A large language model (LLM) agent is powerful but expensive and non-deterministic, so it isn’t the default. Even then, the workflow, not the model, owns every routing decision. The agent might choose which medical code and how confident it is. It doesn’t decide what happens next. A compliance reviewer can read the state machine definition and understand the execution path independent of any agent’s runtime reasoning.

The solution uses AWS Step Functions to orchestrate the coding decision, AWS Lambda for the deterministic steps, and the Amazon Bedrock AgentCore harness for the agentic step. An Amazon Bedrock AgentCore Gateway, a capability of Amazon Bedrock AgentCore, exposes the agent’s tools. Amazon Aurora PostgreSQL-Compatible Edition (Serverless v2) with the pgvector extension serves as a single store for the reference data and its embeddings, so there is no separate vector store to synchronize.

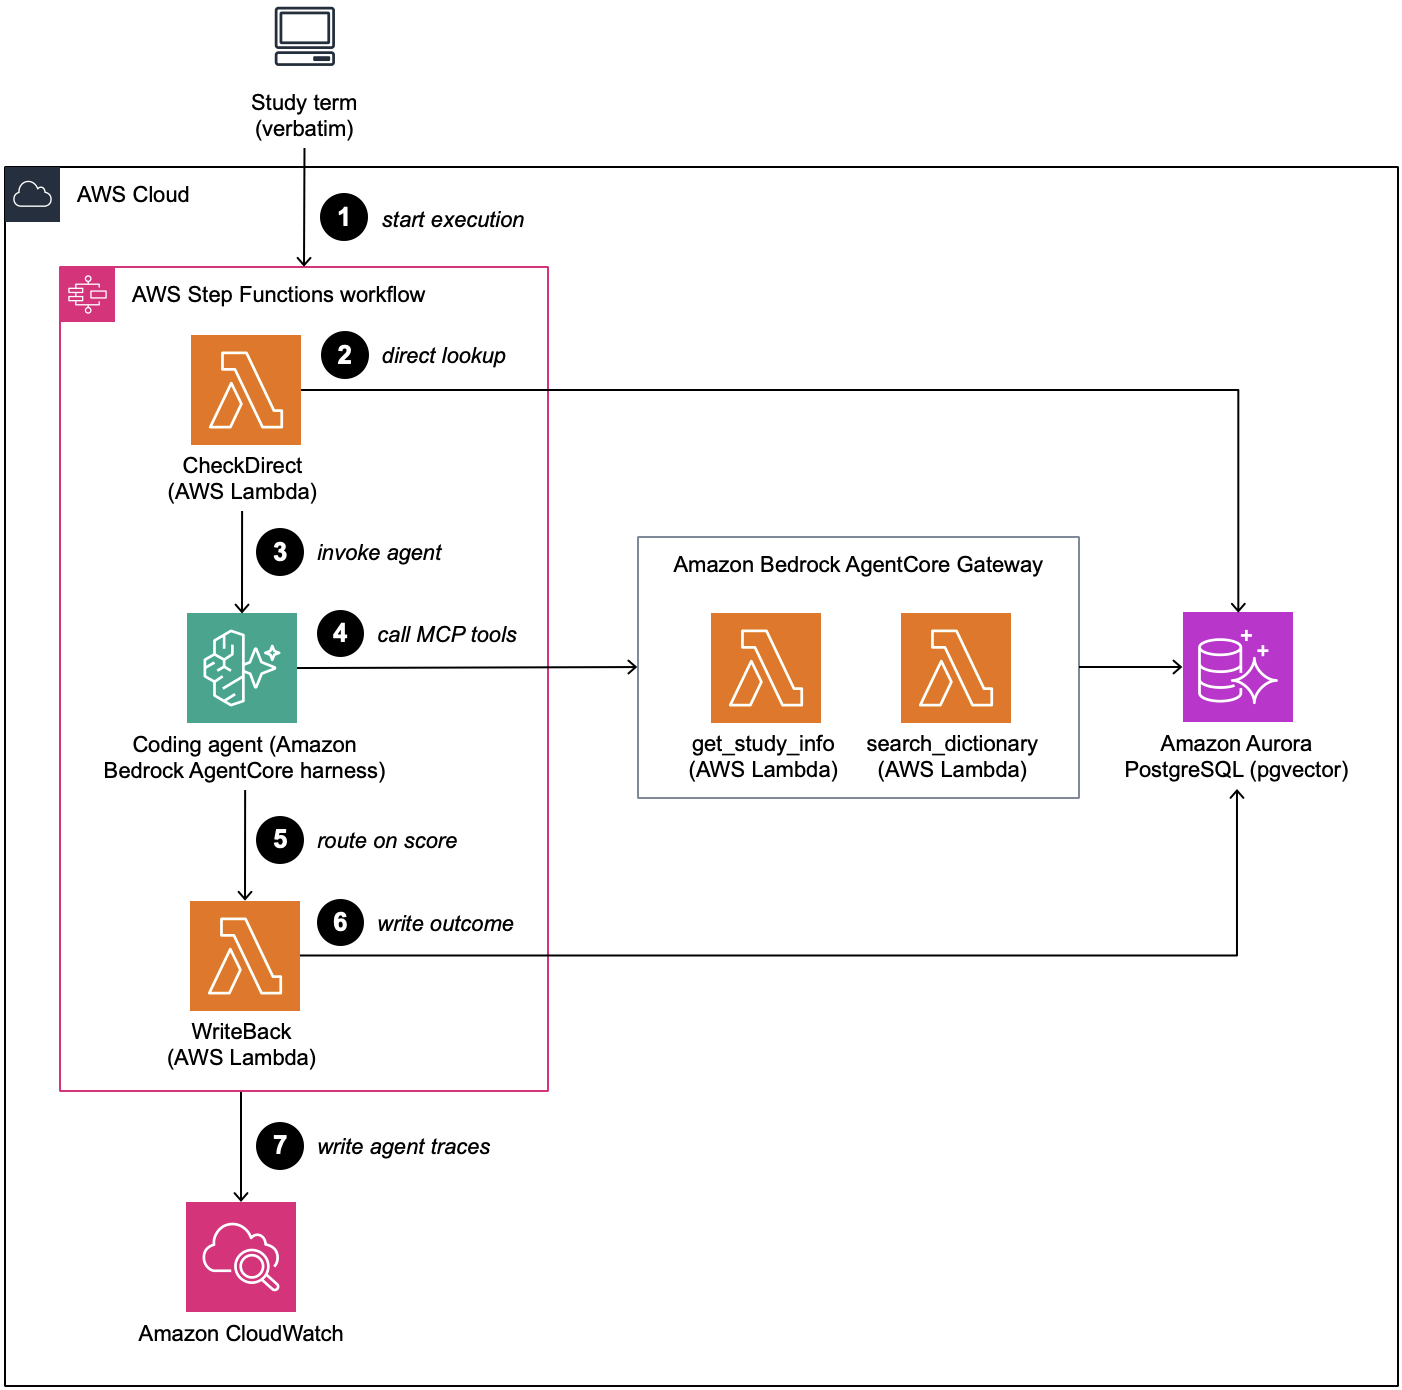
Figure 1 shows the architecture.

A vertical workflow with seven numbered steps. A study term starts a Step Functions execution (1). A CheckDirect Lambda function runs a direct lookup against Aurora PostgreSQL with pgvector (2). On a miss, the workflow invokes the AgentCore harness agent (3), which calls two MCP tools through the AgentCore Gateway (4): get_study_info and search_dictionary. The tools query Aurora. The workflow routes on the agent’s score (5), and a WriteBack Lambda function writes the outcome to Aurora (6). Amazon CloudWatch records agent traces (7).

Figure 1: Medical coding workflow solution architecture

Each Step Functions execution codes one verbatim: a deterministic direct lookup, an agentic semantic search that runs only on a miss, score-threshold routing on the agent’s confidence, and a write-back onto the same study record. The state machine is deliberately a standard workflow. Executions are exactly-once, and the queryable history is a per-term audit trail. For a regulated coding process, answering “why was this term coded this way, by what, and when” is a requirement. Error paths in this sample end with the term left open, so every record gets a terminal status. In production, send errors that survive the retries to a Fail state instead. The execution then shows as failed in Amazon CloudWatch, and you can redrive it after fixing the cause.

The write-back step stores every symptom entry’s full medical family tree, not just an isolated code. For example, a symptom like ‘muscle spasms’ links all the way up to its overarching category, ‘musculoskeletal and connective tissue disorders’. Safety teams can then roll up signals at any level, not just the lowest one. Additionally, the agent logs a one-sentence explanation for its decision. This makes sure that if similar symptoms (like cramps) end up categorized differently across studies, teams can trace the exact study context that caused the variance. They don’t need to guess based on a generic confidence score.

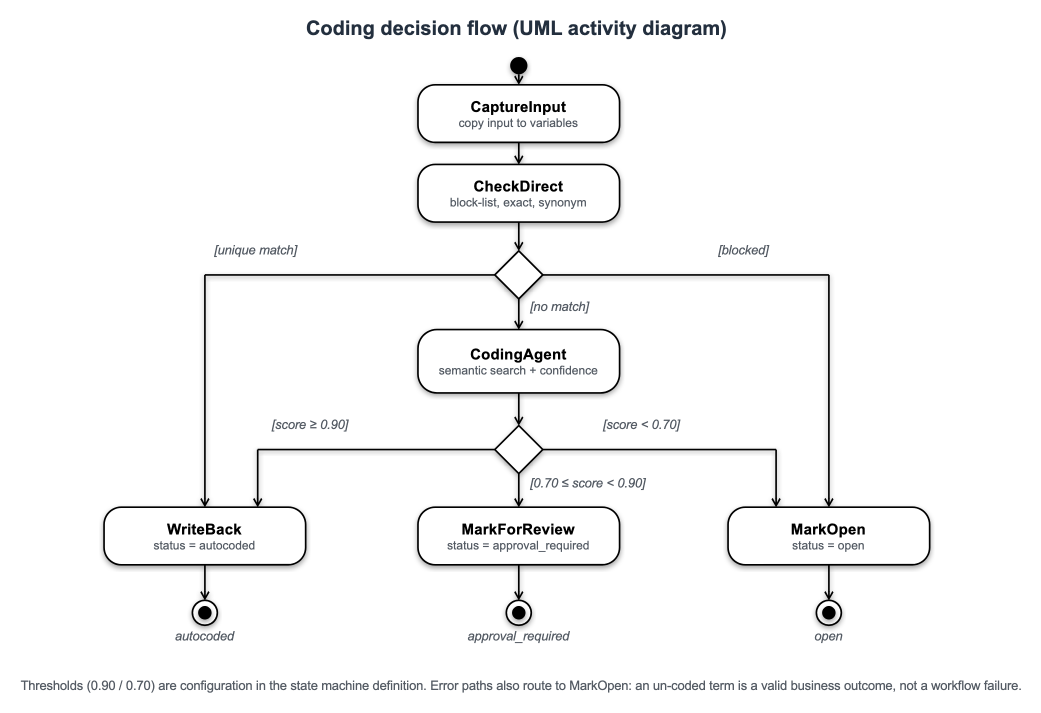
Figure 2 shows the coding decision flow in Unified Modeling Language (UML) activity notation.

A UML activity diagram of the state machine. After CaptureInput and CheckDirect, the RouteDirect decision routes a blocked term to MarkOpen, a unique match to WriteBack, and everything else to CodingAgent. The ScoreThreshold decision routes on confidence: 0.90 and above to WriteBack, 0.70 to 0.90 to MarkForReview, and below 0.70 to MarkOpen. The terminal statuses are autocoded, approval_required, and open.

Figure 2: Medical coding decision flow with the three terminal outcomes in UML activity notation

Note: This sample is for demonstration purposes only and is not intended for clinical use. Before using this pattern in production, validate it against a known-correct dataset and measure coding precision and the incorrect autocode rate.

Walkthrough

The walkthrough follows one verbatim through the state machine, focusing on the architectural decision each stage encodes.

Prerequisites

Before you begin, make sure that you have the following:

  • An AWS account with permissions to create Step Functions state machines, Lambda functions, an Aurora PostgreSQL cluster, Amazon Bedrock AgentCore resources, and AWS Identity and Access Management (IAM) roles.
  • Access to Amazon Bedrock AgentCore in a supported AWS Region. The harness uses Claude Sonnet 5 (us.anthropic.claude-sonnet-5), and the dictionary search uses Amazon Titan Text Embeddings V2 (amazon.titan-embed-text-v2:0). Both models are enabled by default, but Anthropic models require a one-time usage form before first use, which you can submit from the Amazon Bedrock playground. For model availability by Region, see Supported models by AWS Region in Amazon Bedrock.
  • Node.js 24+, the AWS Cloud Development Kit (AWS CDK) CLI, and a bootstrapped target account.

Estimated cost

The largest cost is the Aurora Serverless v2 cluster. It keeps a minimum capacity of 0.5 Aurora Capacity Units (ACUs), so it’s billed for every hour it runs, even when idle. For current rates, see Amazon Aurora pricing. To stop the charges, delete the stack as described in Clean up.

Step 1. Resolve the deterministic cases first

The first task state invokes a Lambda function that makes two checks, in a deliberate order. It first checks a terms-not-to-autocode block-list. These are real dictionary terms, like “HAEMORRHAGE,” that are too broad to auto-assign because the code changes depending on where the bleeding occurred. A hit ends the workflow with the term left open for a human. Because this runs before any model call, it’s a hard control: a safety rule placed ahead of the model cannot be prompted away, and costs nothing to enforce.

The same function then runs a case-insensitive exact match against the dictionary and a curated synonym list (“Hypothyroid” maps to “Hypothyroidism”). A match is accepted only if it resolves to exactly one distinct code. On the sample workload, five of twelve cases finish here: one safety block and four auto codes at score 1.00, each for the cost of an indexed query. More than a third of the workload never reaches the agent at all.

Step 2. Declare the coding agent in the workflow definition

We use an agent for this step because deciding when to pull in study context is judgment, not a fixed rule. In our test run, the agent called the study-info tool only for ambiguous terms and skipped it for a clear typo and for gibberish input. That kind of judgment is hard to encode as a threshold, and the agent can take on new tools later without a workflow redesign. This is also why the agent sits last in line, after two cheaper, deterministic checks.

Only on a miss does Step Functions invoke the agent, using the AgentCore harness optimized integration. The harness resource declares only the model. The system prompt, tools, and allowed tool names are supplied per invocation from the task state. The agent’s full contract is therefore readable in the workflow definition, and there is no container to build or operate. The following abbreviated excerpt shows the shape. See the sample for the full definition. The InvokeHarness Task state has a hard 15-minute execution cap regardless of TimeoutSeconds, so a term needing many tool round-trips could hit it. The sample’s two-tool, single-turn design stays well under that limit.

CodingAgent:
  Type: Task
  Resource: arn:aws:states:::bedrockagentcore:invokeHarness
  Arguments:
    HarnessArn: "${CodingHarnessArn}"
    RuntimeSessionId: "{% $uuid() %}"
    Messages:
      - Role: user
        Content:
          - Text: >-
              {% 'Code this verbatim term: "' & $verbatim & '". Dictionary='
              & $dictionary & ' version=' & $dictionaryVersion
              & ' study=' & $study & '.' %}
    Tools:
      - Type: agentcore_gateway
        Name: gateway
        Config:
          AgentCoreGateway:
            GatewayArn: "${GatewayArn}"
    AllowedTools:
      - "@gateway/search-dictionary___search_dictionary"
      - "@gateway/study-info___get_study_info"
    SystemPrompt:
      - Text: |-
          You are a clinical medical-coding expert...

The agent has exactly two tools, exposed as Model Context Protocol (MCP) tools through an AgentCore Gateway. search_dictionary embeds the verbatim with Amazon Titan Text Embeddings V2 and runs a pgvector similarity search. It searches the verbatim exactly as given, because the misspelling is the signal. get_study_info returns the study’s free-text protocol description. It exists because similarity search can return several clinically plausible candidates it can’t separate on text alone. A human coder breaks that tie using knowledge of the study. This tool gives the agent the same context and nothing else: it returns prose only, not codes.

The clearest illustration is the same verbatim coded in two different studies. “cramps” returns an identical candidate list in both. Only the study description differs. In an oncology study that monitors muscle spasms as adverse events of special interest, the agent coded it to “muscle spasms.” In a reflux study where abdominal cramping is expected and musculoskeletal events aren’t an endpoint, it coded the same verbatim to “abdominal pain.” In this run, the oncology result scored 0.92 and was autocoded, and the gastrointestinal (GI) result scored 0.85 and went to a coder for review. In both cases the agent’s job was to bring the right candidate to the top with a reason a coder can check. That’s how a coder who knows the protocol would decide.

Step 3. Route on coding confidence, not retrieval similarity

The most important design decision is what the threshold routes on. Routing on retrieval similarity, the distance between the two embeddings, is measurably wrong. Table 1 illustrates this with an example.

Verbatim Selected term Retrieval similarity Agent confidence
migrane Migraine 0.37 0.97
flutters in my chest sometimes Cardiac flutter 0.65 0.75

Table 1. Retrieval similarity and agent confidence for sample terms (one run, Claude Sonnet 5)

Table 1 shows the problem. The typo “migrane” looks very different from “Migraine” as text, so its similarity score is low, but the right code is obvious. “Flutters in my chest sometimes” shares more words with “Cardiac flutter,” so its similarity score is higher, but the right code is less certain. Similarity ranks these two cases the wrong way round, and no threshold can fix that. So instead, the agent reports how confident it is in its own choice, using three bands set in the system prompt. It reports 0.95 to 1.00 when the match is clear, 0.70 to 0.94 when the verbatim is vague or the agent needed study context to choose between candidates, and below 0.70 when nothing fits. For example, “cramps” in the GI study could mean muscle cramps or stomach cramps. The agent checked the study description to choose, and reported 0.85, in the middle band. The bands describe the model’s confidence. The 0.90 autocode gate is a separate, fixed rule in the workflow, applied by the Choice state that comes next.

ScoreThreshold:
  Type: Choice
  Choices:
    - Condition: "{% $agentScore >= 0.9 %}"
      Next: WriteBack
    - Condition: "{% $agentScore >= 0.7 %}"
      Next: MarkForReview
  Default: MarkOpen

Note that the routing number is authored by the model. The block-list runs before any model call, and the thresholds are auditable configuration in the state machine definition. The write-back checks the code exists, and anything below the autocode gate reaches a human. Note also that the agent is instructed never to abstain. For gibberish it still returns the top candidate at low confidence, and the gate discards it. The agent scores the candidate, and the workflow decides what happens to it.

Step 4. Write back with a fabrication guard

The terminal task persists the outcome onto the same study record: status, code, hierarchy, score, and a status_changed_by marker that distinguishes machine coding from human action. Before writing, it checks that the chosen code exists in the target dictionary and version. The prompt tells the agent not to invent codes, and this check enforces it. It matters because the agent reads free-text study metadata, which is the kind of input that invites copying a plausible number out of a protocol description. A code that fails the check leaves the term safely open, with the reason recorded. This check has one limit. It can’t tell whether the code was one of the search results, because the workflow only gets the agent’s final response, not what the tools returned. To verify that, look at the agent’s tool calls in AgentCore Observability, a capability of Amazon Bedrock AgentCore.

Deploy and test the solution

The sample deploys with three commands and seeds twelve verbatims that exercise every branch:

npm install && npm run build
npx cdk deploy
npm run seed

Each verbatim runs as one Step Functions execution (the repository README shows the exact CLI calls). The following table shows a live run:

Verbatim Route Score Outcome
HAEMORRHAGE block-list n/a open (safety block)
Dislocated shoulder exact match 1.00 autocoded
Hypothyroid synonym match 1.00 autocoded
ibuprofen exact match (WHODrug) 1.00 autocoded
FULVESTRANT exact match, derivation-only 1.00 autocoded
migrane agent 0.97 autocoded (Migraine)
nexiuum agent 0.95 autocoded (NEXIUM)
cramps (oncology study) agent + study context 0.92 autocoded (Muscle spasms)
cramps (GI study) agent + study context 0.85 review (Abdominal pain)
flutters in my chest sometimes agent 0.75 review (Cardiac flutter)
heart races when I stand up agent 0.80 review (Tachycardia)
asdfghjkl agent < 0.70 open

Table 2. Score and outcome for sample terms (same run as Table 1)

Derivation-only (FULVESTRANT row): a WHODrug ingredient-level exact match, where the write-back updates only the generic-name derivation and ATC hierarchy fields. No new dictionary term is assigned.

The agent skipped the study-info tool for the unambiguous typo and the gibberish and called it only for the ambiguous cases. Every execution’s graph is inspectable in the Step Functions console, and AgentCore Observability records the agent’s tool calls and token usage in Amazon CloudWatch.

Note: Across repeated runs of identical inputs in this sample, the selected code was stable every time, but the confidence score moved within a band. Cases that land near the 0.90 autocode gate can therefore autocode on one run and route to review on another. In our testing, the oncology cramps case scored between 0.75 and 0.92 over six runs. It was autocoded twice and sent to review four times, and Muscle spasms was selected every time. Assert your tests on the selected code, not the exact score, and set your own autocode threshold with margin below 0.90 rather than directly on it.

Scaling beyond one verbatim: This walkthrough codes one verbatim per execution so each decision stays straightforward to inspect. To code a full study, wrap the workflow in a Step Functions Distributed Map state that reads verbatims from an Amazon Simple Storage Service (Amazon S3) manifest, and set MaxConcurrency based on your account’s Amazon Bedrock quota. To size MaxConcurrency, divide your model’s tokens-per-minute quota by the tokens one agent run burns (model calls * (input tokens + 10 * output tokens) for Sonnet 5). Then multiply by the runtime duration in minutes, divide by the share of verbatims that reach the agent, and apply a safety margin. In our testing, 12 concurrent executions against a cluster that had scaled to zero failed 8 of 12 while still reporting SUCCEEDED, which is why the sample keeps a 0.5 ACU minimum and retries the resume errors. Most verbatims resolve in the two deterministic steps, so only a small share ever reaches the agent. For the quotas that apply to your model, see Quotas for Amazon Bedrock.

Clean up

To avoid future charges, delete the deployed resources with npx cdk destroy. All sample data is reseedable, so nothing needs to be retained.

Recognizing the pattern

This pattern fits when the execution path must be reviewable independently of model reasoning, most of the workload is deterministic, only a judgment-heavy minority needs a model, and “escalate to a human” is a first-class outcome rather than an error. It is not limited to clinical trials: the same pattern applies to medical summaries, case narratives, registry intake, study data, and other adjudication workflows such as laboratory test coding, claims triage, and document classification.

You can extend the AgentCore harness with AgentCore Memory to carry context across invocations, Skills to provide task-specific instructions on demand, and AgentCore Gateway to connect MCP servers, knowledge bases, and other tools. Models, tools, and system prompts can also be selected per invocation from the Step Functions task state. Treat a model change like any other release. Rerun your evaluation set, compare the selected codes and confidence scores with the current model’s, and recalibrate the thresholds before you switch. Through all of this, the workflow remains responsible for sequencing and the audit trail.

This isn’t a pattern for open-ended conversations. If the agent must decide what happens next, a workflow engine that owns sequencing is the wrong boundary. Retrieval quality also constrains the agent: if a term isn’t surfaced, it can’t be chosen. In the sample, “flutters in my chest sometimes” would normally be coded to Palpitations, but vector search ranks Palpitations 19th, so the agent does not see it and selects Cardiac flutter instead. The confidence gate still sent it to a coder, but no prompt or study context can recover a term that retrieval never returns. For production dictionaries, use hybrid retrieval, such as lexical search or curated synonym expansion alongside vectors, and calibrate thresholds against your own verbatim distribution.

Conclusion

In this post, we showed how deterministic orchestration and agentic reasoning become complementary when the boundary between them is explicit. AWS Step Functions owns sequencing, thresholds, and the audit trail. The agent owns bounded judgment inside one step and reports a confidence the workflow routes on. The result is a pipeline that codes the common cases for the cost of a query, focuses skilled coders on the ambiguous minority, and routes terms below the confidence gate to a human. The execution history shows exactly which mechanism made each decision. The declarative harness integration keeps the agent inside that boundary as configuration a reviewer can read, not code inside a container.

Next steps

Deploy the sample solution with the AWS Cloud Development Kit (AWS CDK), run the twelve golden cases, then swap in your own reference data and calibrate the thresholds from measured precision. For background, see the AWS Step Functions service integrations, the Amazon Bedrock AgentCore documentation, and pgvector on Amazon Aurora PostgreSQL.

To learn more, see how Step Functions invokes an Amazon Bedrock AgentCore harness from a Task state, the AgentCore harness developer guide, and transforming data with JSONata in Step Functions. To run at study scale, see Distributed Map for large-scale parallel workloads and quotas for Amazon Bedrock. For service details, see AWS Step Functions and Amazon Bedrock AgentCore.


About the authors

Today’s PHP Security Release, and How We’re Strengthening PHP Security (PHP Foundation)

Post Syndicated from corbet original https://lwn.net/Articles/1102060/

The PHP Foundation has put out a
blog entry
explaining how the vulnerabilities disclosed today came
about and why they took so long to fix.

To fix the OOM problem, the PHP security team developed several
competing approaches, but each came with its own trade-offs:
backward compatibility breaks, new denial-of-service potential, or
requiring changes to many third-party extensions which seemed
impossible to coordinate. The PHP security team, operating on
consensus, struggled to choose between these and feared the
repercussions of shipping the wrong choice. Combined with the lack
of a known path to remote code execution and the small team of core
developers with the necessary deep knowledge of the engine occupied
with many responsibilities, this decision process caused work on a
fix to stall and restart repeatedly over months. We won’t pretend
otherwise: the delay was a structural failure, caused by both the
security team’s decision process and its lack of resources.

More vulnerabilities in widely deployed software

Post Syndicated from daroc original https://lwn.net/Articles/1102044/

The Node.js project has
released
a number of security updates
to fix, among other vulnerabilities, a
remote-code-execution bug affecting programs that use Brotli compression. And,
in case any programmers who use compiled languages thought they could relax, the
musl libc project has also announced a
new vulnerability: an
out-of-bounds
write
that could potentially lead to remote code execution, although that
has not been demonstrated.

Best practices for integrating IAM Roles Anywhere with your PKI

Post Syndicated from Abhishek Avinash Agawane original https://aws.amazon.com/blogs/security/best-practices-for-integrating-iam-roles-anywhere-with-your-pki/

Using temporary credentials is a security best practice to reduce the risk from credentials getting compromised. With AWS IAM Roles Anywhere, now your workloads outside of Amazon Web Services (AWS) will be able to access AWS resources by obtaining temporary security credentials in AWS Identity and Access Management (IAM). IAM Roles Anywhere relies on public key infrastructure (PKI) to establish trust between your AWS account and certificate authorities that issues certificates to your workloads that run outside AWS. PKI involves the generation, distribution, and verification of digital certificates through public key encryption.

In this post, we show you some best practices, considerations, and solutions for integrating your PKI with IAM Roles Anywhere. In this post, we assume that you have a foundational knowledge of IAM and IAM Roles Anywhere. For more information, see the IAM and IAM Roles Anywhere documentation.

Note: As of July 2026, AWS Certificate Manager (ACM) supports exportable public certificates that can be used on workloads outside AWS (containers or on-premises). Additionally, ACM supports the ACME protocol for automated certificate issuance and renewal on external workloads. These capabilities complement IAM Roles Anywhere by providing both identity (using X.509 certificates for IAM Roles Anywhere) and encryption (using ACM public/private certificates) for hybrid environments.

X.509 certificates for workload identity

If you’re running multiple workloads in your infrastructure, you’re probably assigning unique workload identities and specific user permissions. In this environment, your workloads can use PKI tools like Active Directory Certificate Services to centrally manage and monitor the identities and permissions at scale. The same principles of segregating unrelated workloads apply to PKI and IAM Roles Anywhere. If you’re issuing certificates to your workloads today, they can probably be used with IAM Roles Anywhere without any changes.

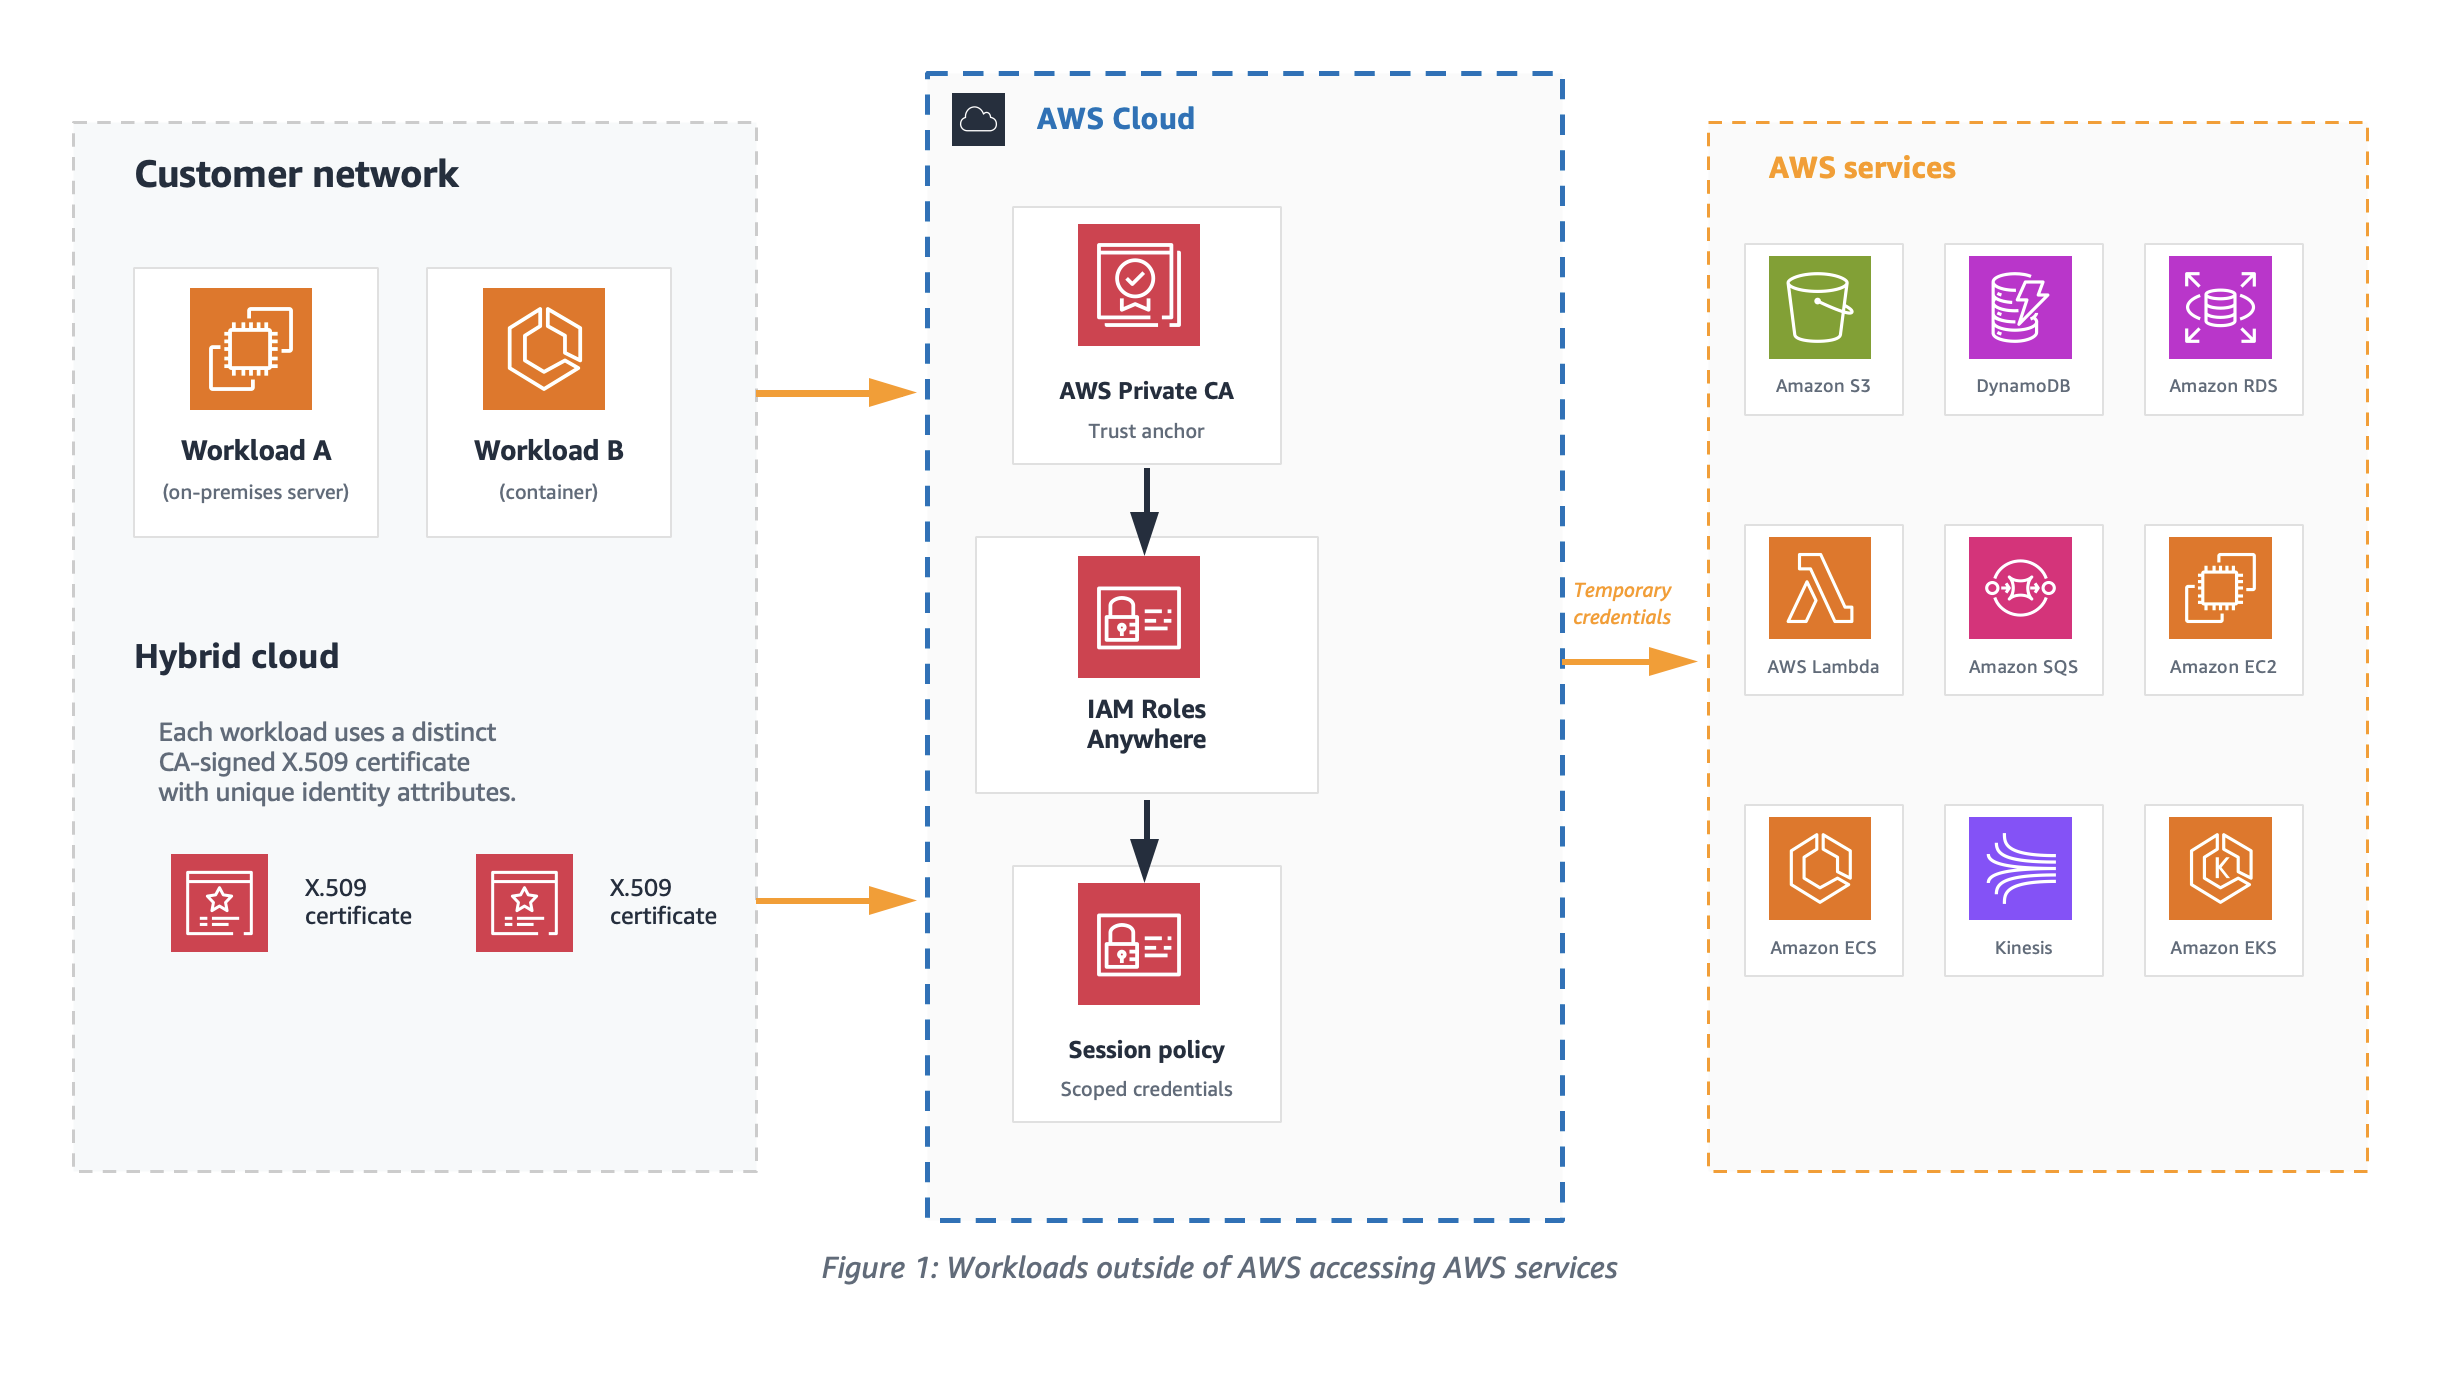
As shown in Figure 1, the access boundary and permissions of Workload A can be very different from that of Workload B when accessing AWS resources, depending on the organization’s needs. In such scenarios, it’s recommended to establish a unique machine identity for each workload. This can be achieved by issuing a separate X.509 certificate with distinct identity attributes signed by your certificate authority (CA). To set up an effective PKI solution for machine identities, you must configure the appropriate certificate attributes and anchor the trust model around those attributes.

Figure 1: Workloads outside of AWS accessing AWS services

Figure 1: Workloads outside of AWS accessing AWS services

Temporary access credentials

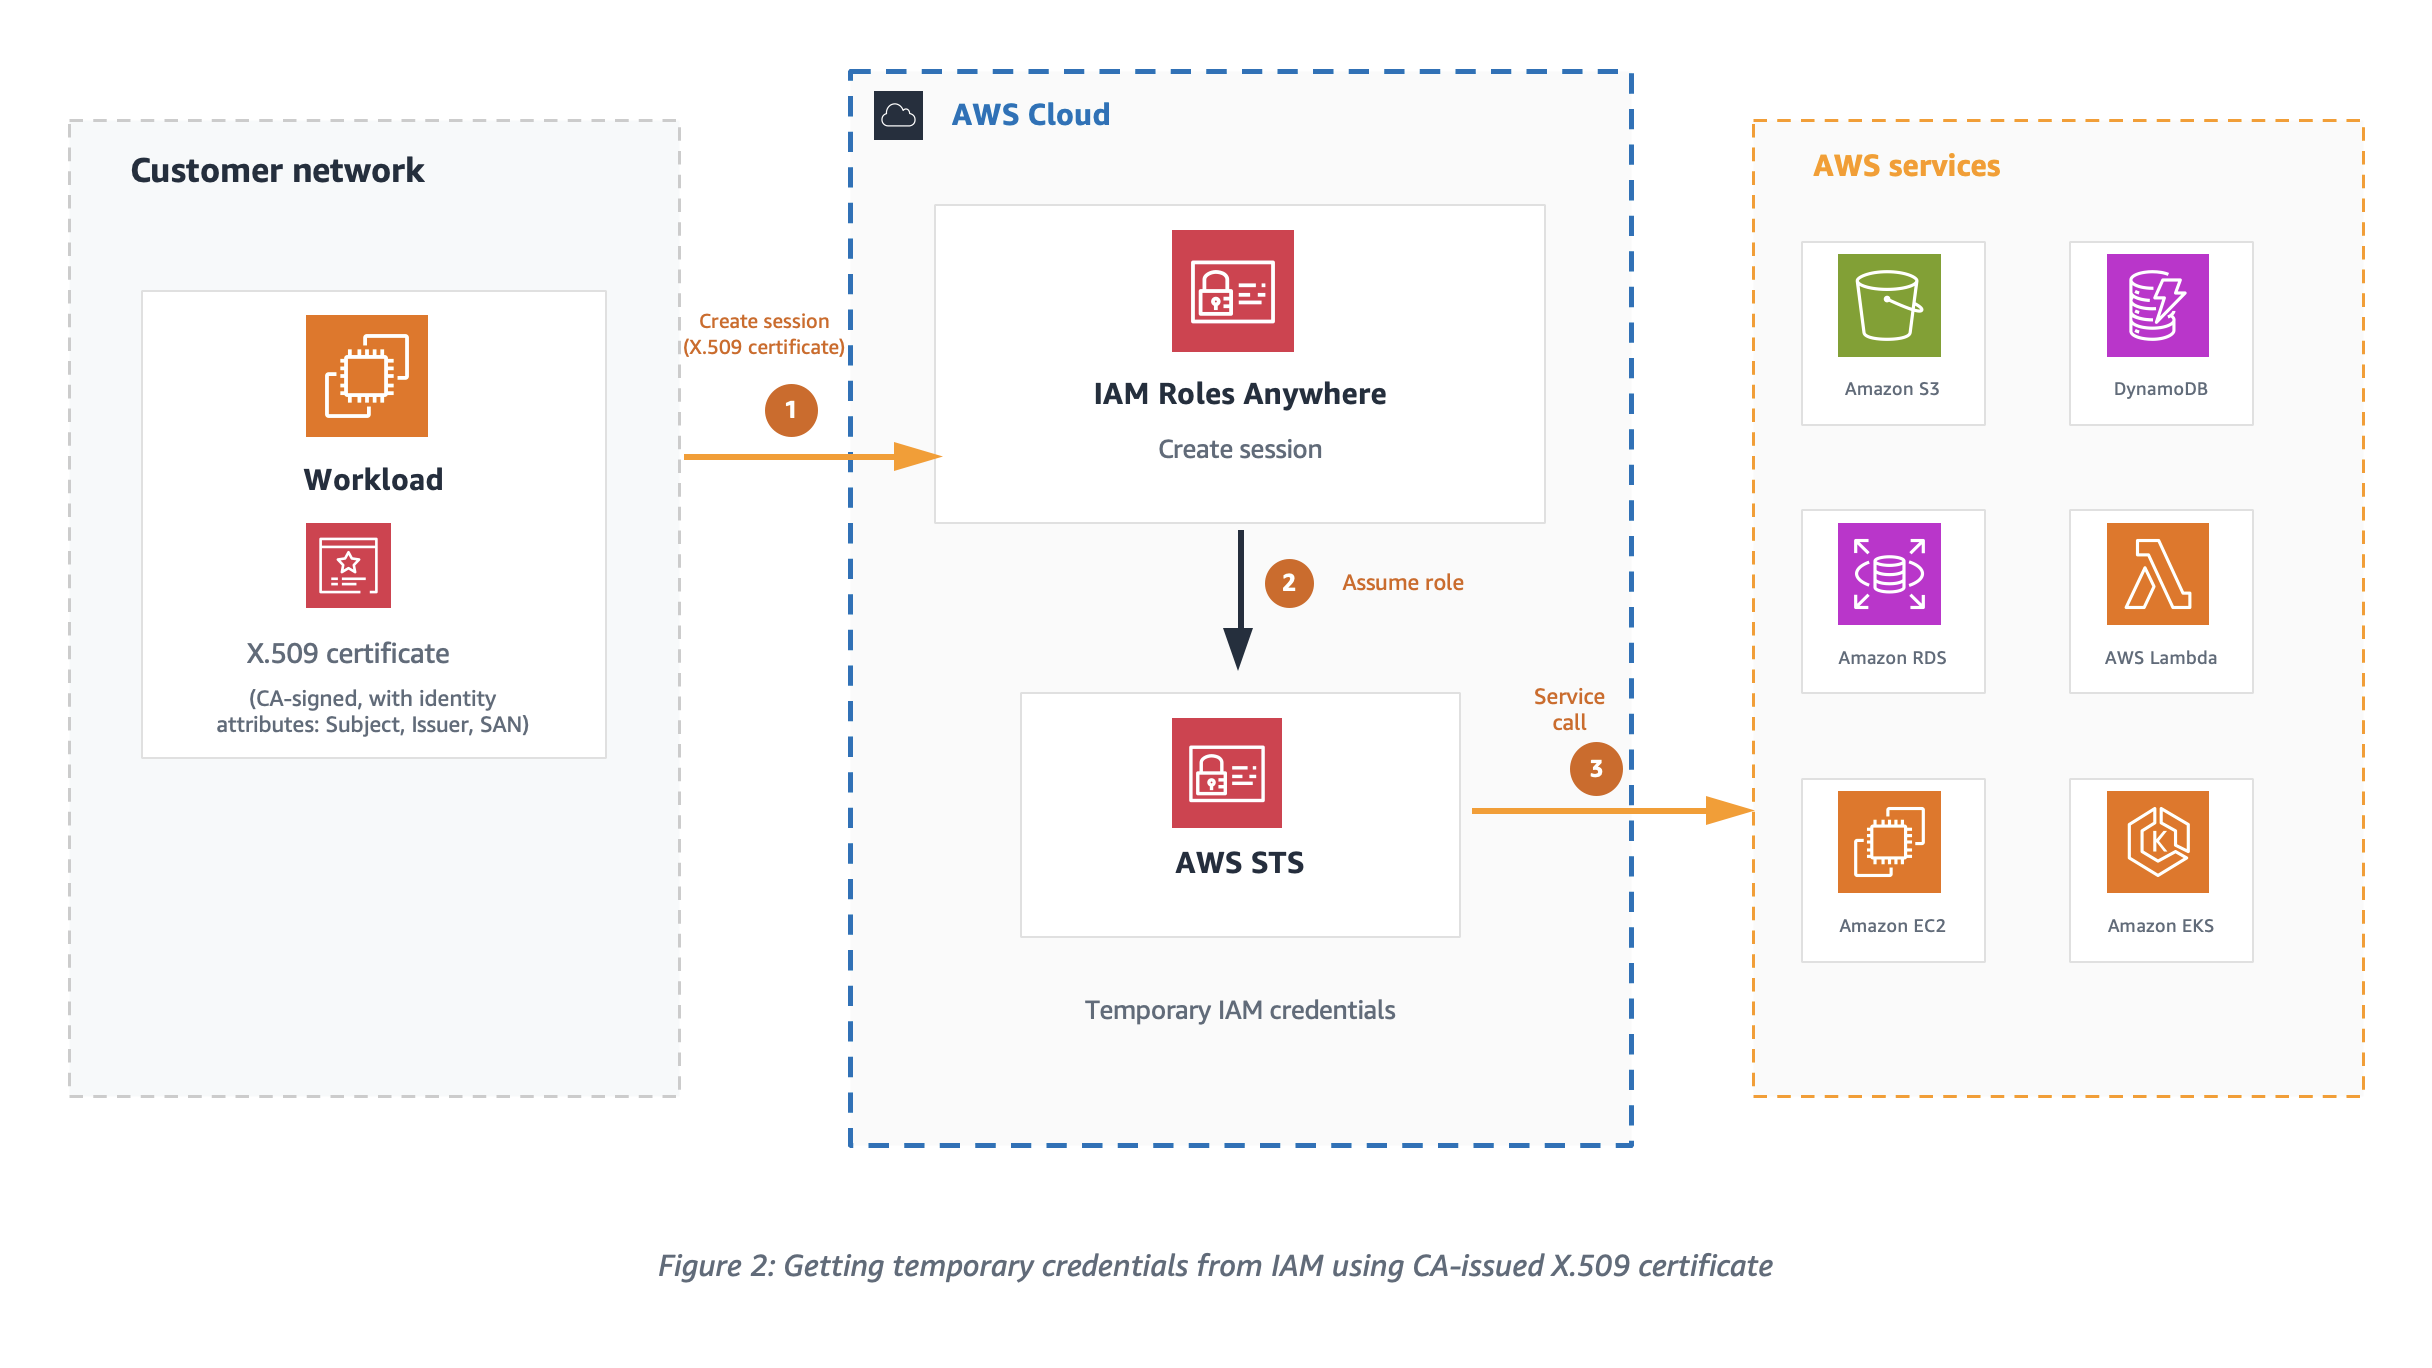
Workloads with distinct CA signed X.509 certificates exchange certificates with IAM, as shown in Figure 2, to get temporary security credentials for the session. The signature validation process used by IAM Roles Anywhere verifies the certificate issuer and the subject before providing the temporary credentials. To enable this verification process, an IAM Roles Anywhere trust model should be set up by either uploading your CA’s digital certificate as a trust anchor or by referencing an existing AWS Private Certificate Authority (AWS Private CA) certificate. In this post, we focus on using a trust anchor.

To help define the appropriate scope for the temporary credentials, it’s recommended to configure distinct IAM roles for each workload to assume. Workloads must use X.509 certificates issued by your CA. These certificates are exchanged with IAM to get temporary security credentials for the session.

Figure 2: Getting temporary credentials from IAM using CA issued X.509 certificate

Figure 2: Getting temporary credentials from IAM using CA issued X.509 certificate

Setting up a trust model for IAM Roles Anywhere is a three-step process, see Extend AWS IAM Roles Anywhere to workloads outside of AWS for more information.

  1. Create a trust anchor.
  2. Set up IAM roles with the IAM Roles Anywhere trust policy that will be assumed by your non-AWS workload.
  3. Configure profiles with IAM roles and attach relevant session policies. This instructs IAM Roles Anywhere to use your selected session policies whenever you request credentials for any of the attached roles.

Trust model

The trust model is centered around setting up the right trust relationship between IAM Roles Anywhere and your CA by configuring a trust anchor. The model connects the role, the IAM Roles Anywhere service principal, and identities encoded in X509 certificates that are issued by a CA.

Certificate attributes

Certificates are a binary record with encoded key/value pairs as certificate attributes. Let’s look at one of the X.509 certificates to understand different attributes of certificate that are important for IAM Roles Anywhere PKI validation.

The following is an example PEM encoded certificate file that can be decoded with tools like openssl.

-----BEGIN CERTIFICATE-----
MIIKOzCCCSOgAwIBAgIQDlnyZvBeKjgHm1jJ++CbgDANBgkqhkiG9w0BAQsFADBE
MQswC ...........
-----END CERTIFICATE----


Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number:
            e0:5d:b7:72:56:fa:75:e3
    Signature Algorithm: ecdsa-with-SHA512
        Issuer: C=US, ST=CA, L=San Francisco, O=MyCompany Inc., OU=AC, CN=MyCompany CA
        Validity
            Not Before: Sep 15 00:09:17 2023 GMT
            Not After : Sep 18 00:09:17 2023 GMT
        Subject: C=US, O=MyCompany, OU=eCommerce, CN=WorkloadA
        Subject Public Key Info:
            Public Key Algorithm: id-ecPublicKey
                Public-Key: (384 bit)
                pub: 
                    04:3b:74:e1:68:06:fa:b0:3d:fe:f7:5f:74:80:05:
        X509v3 extensions:
            X509v3 Subject Alternative Name: 
                DNS:ecommerce.mycompany.com, DNS:*ecommerce.mycompany.com, URI:spiffe://mycompany.com/workload/ecommerce
            X509v3 Basic Constraints: critical
                CA:FALSE
            X509v3 Key Usage: critical
                Digital Signature
    Signature Algorithm: ecdsa-with-SHA512
         30:64:02:30:19:a7:a0:33:49:ce:e1:cb:76:6e:c0:f3:c5:66:

IAM Roles Anywhere extracts values from the subject Common Name (CN), issuer, and Subject Alternative Name (SAN) fields of the authenticating certificate and makes them available for policy evaluation through the sts:sourceIdentity and principal tags. When configuring your PKI, set short validity periods on the certificates issued to workloads. Short-lived certificates limit the window of exposure if a certificate is compromised and reduce the need for active revocation.

"aws:PrincipalTag/x509Subject/CN": "WorkloadA" 
"aws:PrincipalTag/x509Issuer/CN": "MyCompany CA" 
"aws:PrincipalTag/x509SAN/DNS": "ecommerce.mycompany.com" 
"aws:PrincipalTag/x509SAN/URI": "spiffe://mycompany.com/workload/ecommerce" "aws:PrincipalTag/x509SAN/Name/CN": "WorkloadA"

Note: An empty Subject CN in a certificate isn’t supported by IAM Roles Anywhere.

Trust policy and effective permissions of credentials

IAM Roles Anywhere clients fetch temporary credentials for IAM Roles using the API method CreateSession. To successfully authorize this API call, the IAM role trust policy should trust the IAM Roles Anywhere service principal as shown in the following example.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": "rolesanywhere.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession",
                "sts:SetSourceIdentity"
            ],
            "Condition": {
                "StringEquals": {
                    "aws:PrincipalTag/x509Issuer/CN": "MyCompany CA",
                    "aws:PrincipalTag/x509Subject/CN": "WorkloadA",
                    "aws:PrincipalTag/x509SAN/Name/CN": "WorkloadA"
                },
                "ArnEquals": {
                    "aws:SourceArn": [
                        "arn:aws:rolesanywhere:region:account:trust-anchor/TA_ID"
                    ]
                }
            }
        }
    ]
}

As a security best practice, consider using additional condition statements to evaluate the session PrincipalTag attributes extracted from the certificate to further restrict authorization of temporary credentials. If the workloads have ephemeral certificates with a dynamic subject CN, then the issuer or SAN principal tags can be used to define condition statements in the trust policy. The trust anchor shown in the preceding trust policy helps establish the trust between IAM Roles Anywhere and the CA in your PKI.

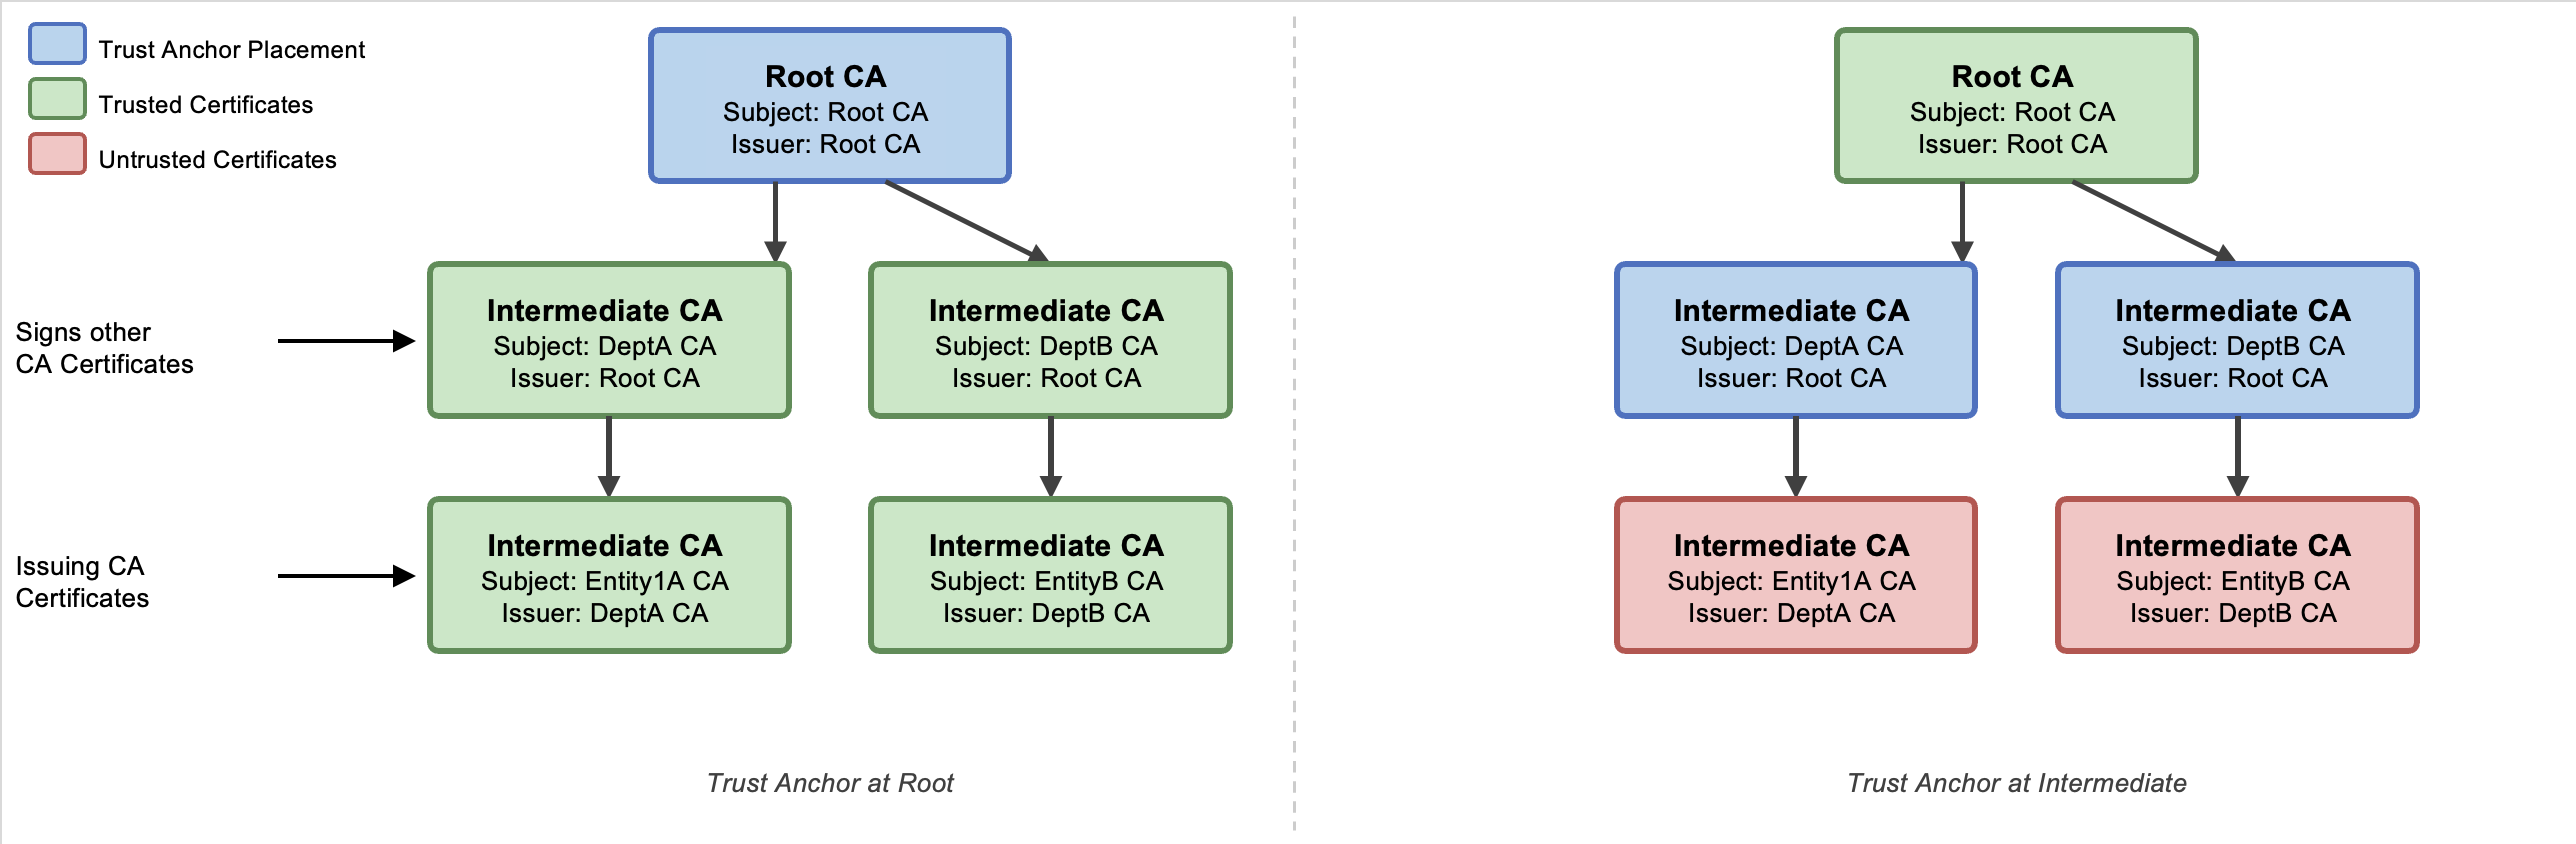
Plan for trust anchor placement

Depending on the CA platform, you can configure one or more intermediate certificates in your PKI certificate hierarchy, as shown in Figure 3. The certificate level the trust anchor is placed at affects which end-entity certificates IAM Roles Anywhere accepts, and therefore which workloads are authorized to assume a role. To create a trust anchor, export the certificate bundle for the issuing CA certificate from your external CA platform in PEM-encoded format and upload it to the trust anchor console.

Figure 3: Certificate hierarchy in an external PKI

Figure 3: Certificate hierarchy in an external PKI

See the Solution deployment section to onboard a sample solution and verify your certificate bundle.

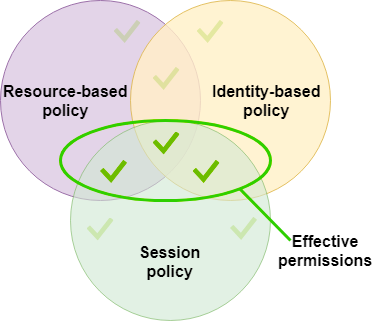
Fine-grained access control is vital for security because it allows organizations to precisely define and restrict permissions, minimizing the risk of unauthorized access and data breaches. The effective permissions of the temporary security credentials are an intersection of resource-based, identity-based, and session policies as shown in Figure 4. By setting up the trust anchor and profile configuration in IAM Roles Anywhere with session policies, you can limit the permissions for each session.

Figure 4: Effective permissions of session credentials

Figure 4: Effective permissions of session credentials

Credential helper

To obtain temporary security credentials from IAM Roles Anywhere, use the credential helper tool. This tool is compatible with the credential_process feature available across the AWS SDKs. The credential helper manages the process of obtaining temporary security credentials using IAM Roles Anywhere and returns them in JSON format. The private key of the workload and its CA signed certificate are the two critical parameters provided to the credential helper tool. To use this tool, you need both an end-entity certificate and a trust anchor created in IAM Roles Anywhere. As of December 2024, the credential helper (version 1.4.0 and later) supports Trusted Platform Module (TPM) 2.0.

The following is an example of how to obtain temporary security credentials:

$ ./aws_signing_helper credential-process \
--certificate /path/to/certificate \
--private-key /path/to/private-key \
--trust-anchor-arn arn:aws:rolesanywhere:region:account:trust-anchor/TA_ID \
--profile-arn arn:aws:rolesanywhere:region:account:profile/PROFILE_ID \
--role-arn arn:aws:iam::account:role/role-name-with-path

When credential-process is used with AWS SDKs, the temporary credentials are stored in memory and refreshed automatically. However, the AWS Command Line Interface (AWS CLI) invokes credential-process on every command. Each invocation creates a new IAM Roles Anywhere session, which adds latency to every CLI call. To avoid this delay when using the AWS CLI, we recommend using the update command, which writes refreshed credentials to a file that the CLI reads on each invocation without calling credential-process again.

When you use update, credentials are written to a credential file on disk and any user or process who can read the credential file might be able to read and use those AWS credentials, so it’s recommended to use serve unless your business has a specific use case that needs to read AWS credentials from a file. The serve command can be used to vend temporary credentials through an endpoint running on the local host using the same URIs and request headers as Instance Metadata Service Version 2 (IMDSv2). When using serve, no AWS configuration files are needed because the AWS SDKs can discover the server endpoint.

Just-in-time compared to short-lived certificates as workload identities

To help mitigate the risk around the exposure of your business-critical resources to compromised certificate user sessions, it’s recommended to use certificates with just-in-time credentials or short-lived access credentials. Just-in-time certificates are issued by a CA for immediate use for authentication on a system or application. The CA uses the roles and policies defined in IAM to determine when, and under what conditions, a workload can establish a session. With just-in-time access, admins don’t have to worry about revoking access if the users’ access roles change. Because the access credentials are recreated for each access request, any role changes can be applied in real time. Just-in-time access requires support from your CA, so verify compatibility with your CA before implementing it.

It’s recommended to tailor the validity periods for short-lived certificates to align with business requirements, workload lifecycle, and your organization’s risk tolerance. AWS Private CA offers a short-lived CA mode specifically designed for certificates with validity periods under 7 days. This mode is priced at $50 per month (compared to $400 per month for general-purpose CA mode), making it cost-effective for high-volume, ephemeral workload identities such as containers and serverless functions. For more information, see AWS Private Certificate Authority and How to use AWS Private CA short-lived certificate mode. See Zero trust on AWS for information about how short-lived credentials support a zero trust architecture.

Best practices for private key storage

Safeguarding private keys is of paramount importance in any environment. A private key is created by the certificate owner when requesting certificates with a Certificate Signing Request (CSR). The CA providing your certificate doesn’t create or have your private key. In fact, it’s recommended that no one outside your administrators should ever be given access to this material. Guardrails should be implemented to make sure the keys aren’t stored in an online repository.

Using the credential helper with IAM Roles Anywhere, you can integrate with PKCS #11-compatible modules. For implementation details, see How to implement cryptographic modules to secure private keys used with IAM Roles Anywhere. With the credential helper (version 1.1.0 and later), IAM Roles Anywhere supports PKCS #11 integration, so you can use private keys stored in hardware security modules (HSMs) or software-based secure stores and avoid storing them to disk. Additionally, as of December 2024, the credential helper supports Trusted Platform Module (TPM) 2.0, enabling private keys to be generated inside the TPM and marked as non-exportable. With TPM-backed keys, the private keys can’t be extracted even if the workload host is compromised. This is the strongest private key protection available for on-premises and hybrid workloads using IAM Roles Anywhere.

If your organization doesn’t implement PKCS #11–compatible modules, IAM Roles Anywhere supports credential helper version 1.0.5 for X.509 certificates and private keys stored in macOS and Windows certificate stores. This delegates the signing operations to keys stored within those OS-specific certificate stores. In Windows, both CryptoAPI and Cryptography API: Next Generation (CNG) are supported; in macOS, Keychain is supported. In these environments, the private key will never be directly readable, and the signing operation would be delegated to the secure store instead, which will improve security posture of your environment. If you have multiple certificates, then use the --cert-selector flag of the credential helper tool to search for a specific certificate (and associated private key) through the certificate subject, issuer, and serial number. The corresponding keys are x509Subject, x509Issuer, and x509Serial, respectively. These keys can be specified either through a JSON file format or through the command line. The following is an example of both approaches:

If you want to use a JSON file, it should be similar to this:

[
  {
    "Key": "x509Subject",
    "Value": "CN=Subject"
  },
  {
    "Key": "x509Issuer",
    "Value": "CN=Issuer"
  },
  {
    "Key": "x509Serial",
    "Value": "15D19632234BF759A32802C0DA88F9E8AFC8702D"
  }
]

If the preceding example is placed in a file called selector.json, it can be specified with the --cert-selector flag through file://path/to/selector.json.

The same certificate selector argument can be specified through the command line as shown in the following:

--cert-selector Key=x509Subject, Value=CN=Subject Key=x509Issuer, Value=CN=Issuer Key=x509Serial, Value=15D19632

Monitoring trust anchor certificates

Monitoring certificate expiry in PKI is crucial for maintaining secure communication, because expired certificates can lead to authentication failures, leaving systems vulnerable to unauthorized access. Compliance and regulatory requirements often mandate timely renewal of certificates, making monitoring certificate expiry essential to avoid legal penalties and maintain organizational integrity.

Using IAM Roles Anywhere, you can receive notifications for CA certificate expiry and end-entity certificate expiry. IAM Roles Anywhere can send metrics, events, and notifications through multiple notification channels as shown in the following table:

Event Channel Threshold Enabled
CA certificate expiry CloudWatch, Amazon EventBridge, and AWS Health 45 days before expiry TRUE
End-entity certificate expiry EventBridge and AWS Health 45 days before expiry TRUE

The preceding notifications thresholds are default settings, which you can customize using the steps in Customize notification settings in IAM Roles Anywhere.

Best practices for trust anchor certificate rotation

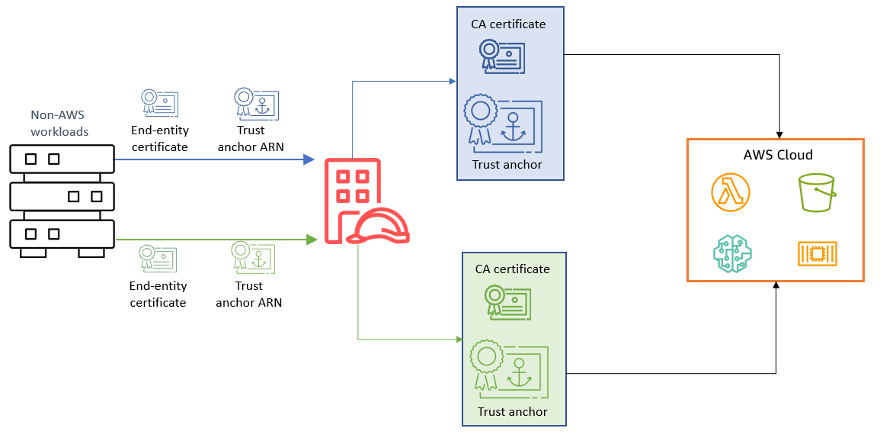
Consider rotating your certificates using blue/green deployments to seamlessly roll out new certificates without affecting service availability. Use automation to integrate certificate rotation testing in your blue/green deployment pipeline. See the sample AWS CloudFormation template in the Solution deployment section to build your automation pipeline.

As shown in Figure 5, two trust anchors have been created; one for each environment. Using this approach, you can test the certificate rotation process in a controlled staging environment before applying it to the production environment, thus reducing the risk of certificate-related outages.

 Figure 5: Trust anchor certificate rotation in blue/green deployment

Figure 5: Trust anchor certificate rotation in blue/green deployment

Solution deployment

The sample solution template is available in the IAM Roles Anywhere — External PKI Integration repository on GitHub. It contains the following main steps:

  1. Creates a distinct IAM role with policies scoped to the resources that workload requires.
  2. Assigns a trust relationship to a IAM Roles Anywhere principal.
  3. Creates a trust anchor using a certificate bundle from an external CA.
  4. Creates a profile with the required IAM Roles.

Parameters for this deployment are shown in the following table:

Parameter Required Default Description
TrustAnchorCertificateBody Yes — PEM-encoded X.509 certificate of your CA (includes BEGIN and END markers)
WorkloadSubjectCN No WorkloadA Subject CN from the workload certificate, used in trust policy conditions
WorkloadIssuerCN No MyCompany CA Issuer CN from the CA certificate, used in trust policy conditions
WorkloadSANCN No WorkloadA SAN CN from the workload certificate, provides additional identity assertion
SessionDurationSeconds No 3600 Maximum session duration in seconds (900–43200)
NotificationEmail No (empty) Email address for certificate expiry notifications. When provided, creates an Amazon Simple Notification Service (Amazon SNS) topic and an EventBridge rule

Important: The SessionDurationSeconds value must not exceed the IAM role’s MaxSessionDuration setting, which defaults to 3600 seconds (1 hour). If you request a longer session than the role allows, the CreateSession API returns an error. The companion template keeps both values in sync by setting the role’s MaxSessionDuration to the same parameter value. If you configure the role separately, update its MaxSessionDuration to match your desired session length. For more information, see IAM Roles Anywhere CreateSession API.

If the workload’s subject CN (WorkloadSubjectCN) doesn’t match the x509Subject CN of the authenticating certificate, the CreateSession call is denied. The same conditional verification applies to WorkloadIssuerCN and WorkloadSANCN.

The template enforces three certificate attribute conditions in the IAM trust policy: issuer CN, subject CN, and SAN CN must all match the values configured as parameters. Additionally, the trust policy scopes role assumption to the specific trust anchor Amazon Resource Name (ARN), preventing other trust anchors in the same account from assuming that role.

Conclusion

In this post, we discussed how AWS IAM Roles Anywhere, empowered by X.509 certificates, introduces a dynamic and secure way to manage workload identities and issue temporary access credentials. By understanding the trust model, using certificate attributes, and implementing fine-grained authorization, organizations can gain granular control over the effective permissions of these credentials.

The choice between just-in-time and short-lived certificates as workload identities depends on your specific requirements.

Adhering to best practices for private key storage is essential to maintain the integrity of your security infrastructure. Regularly rotating trust anchor certificates helps ensure the long-term trustworthiness of your system.

As you embark on your journey to implement IAM Roles Anywhere and integrate it with your PKI, remember that a well-architected approach to certificate management is a cornerstone of robust and resilient cloud security.

For additional deployment guidance, see Planning for your IAM Roles Anywhere deployment, which covers end-to-end deployment planning including network architecture, monitoring, and operational considerations.

If you have questions, you can start a new thread on AWS re:Post or reach out to AWS Support.


Abhishek Agawane

Abhishek Avinash Agawane

Abhishek is a Security Consultant at Amazon Web Services with more than 8 years of industry experience. He helps organizations architect resilient, secure, and efficient cloud environments, guiding them through complex challenges and large-scale infrastructure transformations. He has helped numerous organizations enhance their cloud operations through targeted optimizations, robust architectures and best-practice implementations.

Manoj Gupta

Manoj Gupta

Manoj is a Senior Solutions Architect at AWS, based in San Francisco. With over 4 years of experience at AWS, he works closely with customers to build optimized AI/ML powered solutions and cloud infrastructure. His primary focus areas are data, AI/ML, and security, helping organizations modernize their technology stacks. Outside of work, he enjoys outdoor activities and traveling with family.

NVIDIA GTC Berlin 2026 NVIDIA Intros DSX PODs and More

Post Syndicated from Ryan Smith original https://www.servethehome.com/nvidia-gtc-berlin-2026-nvidia-intros-dsx-pods-and-more/

NVIDIA kicked off GTC 2026 with its lead keynote. Among the highlights for this year’s European NVIDIA tradeshow are the DSX POD, a server-in-a-container, as well as a slew of software updates for the NVIDIA ecosystem

The post NVIDIA GTC Berlin 2026 NVIDIA Intros DSX PODs and More appeared first on ServeTheHome.

[$] Hash-based module integrity for reproducible distributions

Post Syndicated from jake original https://lwn.net/Articles/1100026/

We last looked in on hash-based integrity
checking for kernel modules
just over a year and half ago. Since that time,
the patch
set
has undergone multiple revisions. At the 2026 Linux Plumbers Conference
(LPC), Thomas Weißschuh described the need for kernel-module integrity
guarantees while still providing reproducible builds, how his patches implement that, and some ideas for possible
further work.

The bridge to agent-scale Git infrastructure

Post Syndicated from Eleanor White original https://github.blog/engineering/architecture-optimization/the-bridge-to-agent-scale-git-infrastructure/


Over the past year, while Git traffic grew exponentially, 99.99999% of the Git repositories on GitHub began living in two places at once: our own data centers and Azure. The rest are among the busiest on the platform, and they’re held back by just one thing: a 25ms round trip.

In an earlier blog post, we laid out the two principles behind our next-generation storage architecture:

  • Minimize coordination
  • Decouple storage from compute

In this post, we’ll look at the immediate bridge between our old design and our new one. We’ll talk about how a change to the way our quorum serializes writes gets the busiest repositories into Azure, and how that same step opens the door to replicas that keep no persistent state of their own.

How we got here

The timing and shape of the move were driven by the agentic shift: rapidly growing traffic, a hard ceiling on the power capacity of our data centers and the surrounding geographical region, and physical supply chain constraints. At the beginning of our migration, the remaining capacity with all possible expansion gave us enough time to migrate safely, but not enough to do it slowly.

While we had prototyped new architectural approaches for scaling Git on cloud infrastructure, changing the storage architecture and the hosting platform at the same time, under that growth, carried too much risk. Given our scale and how critical the service is to the community, we needed to sequence the work carefully: move the data first, then evolve the architecture once it arrived.

Git operations are a Tier 0 service: they’re a core function of GitHub, and nearly everything in GitHub depends on the repository data. That meant the data, services, and every dependency had to move first. The first copy of a repository landed in Azure’s Central US region in August 2025. Today, most repositories have two of their five replicas in Azure, and Azure serves about half of Git traffic. For most of that time, Azure absorbed our growth while our own data centers held steady.

During the migration, traffic follows the data. Most repositories have five replicas to balance durability, availability, and scale. To minimize read latency, Spokes uses preferential routing to direct traffic to a replica in the same region and availability zone as the request. As replicas move to Azure, the share of the traffic that can be served from Azure grows with each one, until the last replica arrives and the old region stops receiving requests entirely. Every repository goes through this process:

No repository left behind

So, what about the remaining 0.00001% of repositories?

In our current architecture, a repository hosted in more than one region has a lower write throughput ceiling. Spokes’ quorum only needs a majority to commit a write, but it waits for every healthy replica to respond (up to a timeout) before moving on, so slow replicas delay every write rather than falling behind. In practice, that means the slowest healthy replica sets the latency of every write, and because each write holds a repository-wide lock until it commits, it also sets the throughput ceiling. Once a replica lives in the target Azure region, it’s about 1,000 miles from our data centers, making each network round trip around 25ms, and a write requires multiple round trips. A repository already near its throughput ceiling can’t absorb that on every serialized write; it would fall further behind with every push.

This is where our first principle, minimizing coordination, comes into play. Specifically for this case: don’t serialize what doesn’t need to be. Git’s consistency requirements apply to each reference individually. Once the server accepts an update to a reference, no client should see an older value afterward, only that value or a newer one. That holds whether the update is a fast-forward, a force push, or a delete. But in most cases, updates to different references don’t depend on each other and can be applied independently.

So, we’re changing the scope of the quorum from the whole repository to individual references.

Holding a repository-wide lock for the entire reference update, round trips included, turns the quorum into a single, unordered request queue with one write in flight at a time. Each write in that queue takes as long as the slowest healthy replica. As the write rate grows, so does the queue, and each write waits longer than the one before it.

With per-reference serialization, only writes that contend on a shared reference must wait for each other. In practice, most writes to a repository touch different references—for example, agents and developers pushing to their own branches—so they no longer wait on each other. Each write still experiences the cross-region latency but writes to different references can be in flight at the same time. That removes the single bottleneck on the repository. We can visualize how queueing and timeouts build up by comparing the two approaches side by side under similar load:

These changes raise a repository’s write throughput ceiling roughly in proportion to how many references are being written at once, and get the last remaining repositories into Azure. In internal testing with realistic traffic, writes to different references consistently saw 3–4x higher throughput at lower latency.

Scaling reads on their own

Most repositories are heavily read-skewed, with somewhere between 100 and 1,000 reads for every write. Today, reads and writes hit the same replicas, so they compete for the same resources and can’t be scaled independently.

Decoupling storage from compute changes that. Once repository data is durably stored in Azure Blob Storage and updated with each incoming write, we can begin to decouple read traffic from the write quorum, and independently scale the compute needed for each. For example, reads would benefit from far more in-memory cache than we give them today, but that memory is also needed for compaction. Once they’re separated, each gets its own configuration.

The first step is making object storage a member of the quorum, but a special one that we call a virtual replica. The compute that represents it is our first fully ephemeral node. It serves as a bridge to object storage, streaming incoming writes and serving no reads. Because it’s a member of the quorum, a write isn’t acknowledged until it’s durable in object storage.

That adds a little latency to each write, but just like the cross-region round trip, per-reference serialization keeps it from becoming a throughput bottleneck. The virtual write replica also coalesces transactions on disjoint references into a single set of network I/Os to object storage, so a busy repository pays for one round trip across many concurrent writes instead of one per write. For now, the virtual write replica also handles compaction, and read replicas inherit the compacted state.

With the virtual write replica in place, we can scale out as many virtual read replicas as a repository needs, on demand. Each read replica warms its cache from Azure Blob Storage and starts taking read traffic without joining the quorum, using object storage as the source of truth and reconciling its local state against it in the background.

This step unlocks significant read scale. In internal testing, our distributed load testing harness routinely found ceilings in the current architecture. Against virtual read replicas, the harness hit its own limits first. It also comes with a few challenges that are solved in subsequent steps:

  1. Virtual read replicas start out reconciling with object storage in the background, which makes them a good fit for some read workloads but not all of them. Serving every kind of read requires moving that reconciliation in-line, fetching only the reference state and data that changed since the replica last caught up.
  2. While we’ve incrementally increased write throughput by shifting to a per-reference model, the quorum remains the bounding factor for increasing further.

How can we push write throughput further?

What comes next

The GitHub of today was built on the Spokes quorum, and over the years Spokes has become much more than a quorum coordinator. It’s also an intelligent routing and load balancing layer, a unified API that internal clients use to access and transact repository data at well over 100 billion operations per day, and a collection of background systems we call “sweepers” that handle repository placement, repair, and rebalancing between storage nodes.

The vast majority of what lives under the Spokes service umbrella applies just as well to the new architecture as it does to the existing one. But we also recognize that the commit protocol that has taken GitHub to a billion repositories won’t take it to the next billion and beyond.

We’re not done yet. With these steps in place, the next limit is write throughput. Every write still waits on replicas that each hold a full copy of the repository, yet very little of a write actually needs to be ordered. Git objects are immutable and named by their contents, so they can be stored without anyone agreeing on them. What’s left is small, and the hard part is ordering it as fast as possible without moving the bottleneck somewhere else. Designing for that on a whiteboard is one thing. Doing it underneath a billion repositories that developers and agents are writing to around the clock is another. Getting there forced us to rethink the second-order effects too, like where durable reference state lives and how compaction and garbage collection scale.

Agent traffic isn’t slowing down, and each of these steps gives repositories more headroom as it lands, without waiting for the end state.

Coming next week: At GitHub Universe and in the final post in this series, we’ll take a tour through that end state, what it does for write throughput, the second-order problems we had to solve to get there, and why there’s still a (small) consensus group somewhere in the stack.

Thanks to Brian Celenza for their contributions to this post.

The post The bridge to agent-scale Git infrastructure appeared first on The GitHub Blog.

Кафе, боб и предизборни прогнози

Post Syndicated from Александър Драганов original https://www.toest.bg/kafe-bob-i-predizborni-prognozi/

Кафе, боб и предизборни прогнози

За политолозите и социолозите се знае, че колкото и пъти да сбъркаме с прогнозите си, дойде ли време за избори, се пробваме отново и отново. В началото на 2026 г. смело предвидих как едва ли някога отново ще имаме победител с абсолютно мнозинство, само за да бъда опроверган от „Прогресивна България“ на Радев три месеца по-късно. Сега отново опитвам да прогнозирам изхода от президентския вот, макар оперативната обстановка (както казваше навремето мой колега политолог с познанства в МВР) да е динамична и пълна с черни лебеди – всъщност дронове, които от време на време потапят българските кораби.

Нашата власт в усърдието си да не обиди никого според мен е на път да реагира като пиратите от анимацията „Астерикс в Британия“, които накрая сами продъниха кораба си, само и само да не свършат тази работа галите. В нашия случай (с висока степен на вероятност, както биха казали управляващите) – руснаците.

Да се върнем обаче на изборите за президент. Макар някои от основните партии и коалиции (ГЕРБ–СДС и ДПС), както и други по-малки, но обичайни заподозрени (например „Синя България“) да не сметнаха за необходимо да участват в тях, кандидатите за държавен глава са рекорден брой – 28. Социологическите проучвания обаче отличават трима от тях с по-големи шансове, а подкрепата за още няколко е що-годе видима. 

С уговорката, че това не са прогнози кой ще победи, а „моментна снимка“ на обществените нагласи. 

Като фаворит в битката влиза Илияна Йотова, която изпълнява длъжността президент след оставката на Радев, с кандидат-вицепрезидент Кирил Вълчев, а като основен съперник се очертава двойката на Андрей Гюров и Георги Кандев. И двете кандидатури са издигнати от инициативни комитети, макар зад тях да застават партии. Както каза Йотова, тя разчита на най-старата (БСП) и най-младата партия („Прогресивна България“). Зад Гюров са наскоро разделилите се ПП и ДБ, които обаче са заедно в негова подкрепа. Според социологическите изследвания Гюров и Кандев не само привличат симпатизантите, но и популярността им надхвърля общата подкрепа на двете политически сили за евентуален предсрочен парламентарен вот.

На трето място агенциите посочват тандема Костадин Костадинов и Петър Волгин от партия „Възраждане“, а зад тях са подобните им по убеждения двойки, водени от Радостин Василев („Меч“) и Ивелин Михайлов („Величие“). Демократичното пространство не изневерява на традицията да вади алтернативни на основните си кандидати в лицето на Иван Христанов и Николай Ненчев. В надпреварата участват и вечни претенденти като Волен Сидеров, проф. Александър Томов, Венци Чикагото, както и наистина екзотични кандидатури като Ваня Великова и Величка Георгиева – последното можем да го кажем като скоропоговорка. Тези Кубертенови участници в голямата си част нямат шанс не само за победа, а дори за балотаж, но стават за разпространение на руски опорни точки. Ако приемем мрачната хипотеза, че активността на много от тях зависи от един център, опитващ да доминира публичната среда, можем да окачествим стратегията на този център с английската поговорка, че мяташ всичко по стената с надеждата нещо да залепне.

Йотова – когато милостта се окаже недостатък

Илияна Йотова влезе в кампанията с институционална тежест и внушителен инициативен комитет, в който се включиха както личности със значителен авторитет – като проф. Христо Пимпирев и Симеон Идакиев, така и призраци от миналото, като Красимир Каракачанов от ВМРО и Красимир Премянов от Съюза на тракийските дружества, който по времето на Жан Виденов беше лидер на парламентарната група на БСП и минаваше за един от силните хора в партията. 

От самото начало обаче набраната инерция заскърца заради разкритията, че Йотова е помилвала наркотрафикант. По-късно се разбра, че това не е единичен случай. Тя прехвърли отговорността за решението си на медицинска комисия. Така, без да иска, сама се сведе до ролята на прословутата автоматична писалка, която президентът на САЩ Доналд Тръмп не спира да използва като подигравка срещу предшественика си Джо Байдън, както постъпи дори пред китайския си колега Си Дзинпин. 

Оставам с впечатлението, че умението да се справя в състезателната обстановка не е особено силна страна на Илияна Йотова

и тя до голяма степен очаква коронация на изборите. В този стил беше и интервюто ѝ пред Георги Любенов – в помещение, напомнящо тронна зала. Такава увереност придава тежест, но издава и известно високомерие.

Кирил Вълчев беше избран за кандидат-вицепрезидент, за да добави интелектуална тежест към кандидатурата на Йотова. Директор на БТА, възпитаник на НГДЕК, дългогодишен журналист, умеещ да говори красиво. На този фон изцепката му, че ще се бори с арабските цифри, е покъртителна. Може би на фона на общия патриотарски популизъм героичната кауза за борба в защита на кирилицата от несъществуващи врагове, подета от президентката, е хитър ход. Добавянето на цифрите към враговете обаче го превръща във фарс.

Според социолозите подкрепата на Илияна Йотова е над 40%, а според някои прогнози доближава 50%. На пръв поглед това звучи озадачаващо, тъй като „Прогресивна България“ позагуби част от подкрепата си, традиционните националисти върнаха някои от гласовете, дадени напролет за Радев, и въпреки това изглежда, че действащата президентка върви към сходен или по-висок резултат. Това може да се обясни с прогнозираната по-ниска избирателна активност. При такова развитие е възможно Илияна Йотова да има по-нисък резултат от партията на Радев като абсолютен брой гласове, но да има същия или дори по-висок дял от подадените бюлетини. 

Основен актив на настоящата президентка са умерените русофили,

които искат да следват максимата, приписвана на цар Борис III (без да има доказателства, че той я е изрекъл) – „Винаги с Германия – никога против Русия“. За тях политиката на „Прогресивна България“ и лично на президентката Йотова е реванш след последните години на подкрепа за Украйна, като в същото време те не желаят да се загърбят напълно ЕС и НАТО, както искат симпатизантите на „Възраждане“. Дали тази позиция е разумна, е спорно, но тя, изглежда, намира сериозна подкрепа сред гласоподавателите, така че носи дивиденти на двойката Йотова – Вълчев.

Основният негатив на Йотова е, че доколкото е свързвана с Радев, върху нея се прехвърлят известни имиджови щети от провала в борбата с поскъпването – основен бич за избирателите у нас и по света. Самият спад и отказът от гласуване, наблюдавани от социолозите, сочат, че се оформя недоволство, което при евентуален балотаж може да избие срещу Йотова.

Гюров – кандидатът, от когото ПП и ДБ имаха нужда

Не е тайна, че „Продължаваме промяната“ и „Демократична България“ разчитат на електорат, който трудно би ги напуснал заради популистка формация, но почти невъзможно е периферията им да се разшири. Яростната антикорупционна реторика и реторическото „влизане с бутонки“ на опонентите, характерно както за Асен Василев от ПП, така и за Ивайло Мирчев от „Да, България“, надъхва симпатизантите, но може да отблъсне колебаещите се.

От тази гледна точка изборът на Андрей Гюров се оказа великолепен.

Той защитава позициите на ПП и ДБ убедено, но разчита на спокойна, експертна реторика, говори, без да повишава гласа си, демонстрира двустранна комуникация, при която общува с избирателите, а не ги назидава отгоре. Последното е видно и от клиповете, които споделя. В тях се вижда, че Гюров успява да запази самообладание дори при агресивен противник от другата страна. Защитава ясни проевропейски и прозападни позиции, но като че ли опитва да убеди и колебаещите се в тях, а не разчита на назидателното „трябва да мислите така“. 

Като минус на Андрей Гюров може да се отчете, че експертният му маниер на говорене често не е особено увлекателен.

Понякога думите му не може да се обобщят накратко и така да достигнат и до хората с по-повърхностен интерес към политиката.

По-сериозен гаф беше прословутото интервю, в което Гюров се затрудни да посочи агресора във войната с Иран. Но това се случи относително рано в кампанията и остана на заден план на фона на положителното му като цяло излъчване. Компетентността на кандидата за вицепрезидент Георги Кандев беше подложена на съмнение, но номинирането му има потенциал да привлече избиратели на ГЕРБ, които предвид миналото на Бойко Борисов симпатизират на образа на строг полицай с чувство за хумор.

За момента данните показват, че Андрей Гюров има доста висок прогнозен резултат – между 20 и 30%. Ако се потвърди на изборите, това ще означава, че задачата да бъдат привлечени бивши „сини“ избиратели, отишли в ГЕРБ, е по-скоро изпълнена, при все многото знакови лица от партията, подкрепили Йотова. В случай че резултатът на кандидатите на ПП и ДБ прехвърли 30%, а Йотова и Вълчев паднат под 40%, това би направило балотажа по-трудно предвидим. Чисто инерционно настроенията ще се насочат към Гюров и Кандев и тогава може да сработят механизми, които излизат извън механичното пресмятане кой от другите към кого би се присъединил. Йотова ще трябва да разчита най-вече на избирателите на „Възраждане“, но при сходна ситуация на последните местни избори в София Костадин Костадинов отказа да подкрепи Ваня Григорова. 

Костадинов пред Волгин – его или стратегия?

„Възраждане“ преживя тежък удар на парламентарните избори, когато едва прескочи бариерата от 4%. Ходът с включването на Петър Волгин в президентската надпревара обаче е нож с две остриета. Ярък глас на соцносталгиците у нас, Волгин има потенциал да откъсне част от подкрепата за Йотова. Като кандидат за вицепрезидент обаче този му потенциал е ограничен. И тук идва въпросът дали Костадин Костадинов не направи грешка, като не пусна Волгин например с Нешка Робева, за да играе ако не за победа, то поне за балотаж. 

За Костадинов обаче оцеляването на партията му и лично на него като неин лидер може да е от по-голямо значение от доброто представяне конкретно на тези избори.

С личното си участие той се опитва да стабилизира доверието към „Възраждане“ и конкретно към себе си, да увеличи резултата спрямо парламентарния вот и да успокои симпатизантите си. Със сигурност много от избирателите на партията таят надеждата, че ще успеят да повторят постижението на Сидеров и „Атака“ отпреди двайсет години, макар социолозите да не дават сериозни индикации, че това е възможно. В миналото партия „Възраждане“ често е била подценявана, както често се случва с партии, вотът за които се смята за обществено непрестижен. Напоследък обаче симпатизантите ѝ са по-скоро горди с нея, така че този ефект е минимизиран. Ако има скрит популистки вот, той според мен ще се прелее другаде.

Имат ли скрит потенциал Ивелин и Радостин?

Най-трудно е да се предвиди резултатът на малки партии – понякога той носи изненади. В миналото и „Меч“, и „Величие“ са показвали, че могат да постигнат по-висок резултат от видимия за социолозите. Причините според мен са в достигането до нетрадиционни избиратели.

Радостин Василев има ясна и простичка стратегия. Яко хейт и много хумор, ако ми позволите разговорния език. Той се стреми да оплюе всичките си опоненти и да нарича с цветисти изрази управляващите. Силата му е, че може да изговори това, което би било недопустимо за Андрей Гюров например. Разчита и на подигравки, което се харесва на българите, видно от резултатите на „Има такъв народ“ в миналото, от чиито редици изгря и Василев. Възможно е да привлече гневни млади мъже с антикорупционната си реторика и да постигне по-висок резултат от предвиденото. Но е трудно да си го представим на балотаж.

Ивелин Михайлов има още по-странна стратегия. Неговата бизнес империя като че ли рухна, но той използва това, за да си създаде образа на мъченик. Голямата му слабост е, че не може да говори особено интересно и увлекателно. Това се компенсира с абсурдни клипчета, правени с изкуствен интелект и разпространявани в интернет от структури на „Величие“. В тях той се изявява като Нео от „Матрицата“, бори се с триглав змей, носещ лицата на политици от статуквото и т.н. Звучи смешно, но има потенциала да привлече електорат, който традиционно не е изкушен от политиката, но би могъл да бъде привлечен да се включи в изборите посредством похвати от комиксовата култура. Това прави прогнозния му резултат сходен с този на Радостин Василев – по-висок от първоначално очаквания, но недостатъчен за нещо значимо.

От останалите кандидати известен потенциал на теория има Иван Христанов, но ми се струва, че неговата реторика е популистка, а се цели в електората на демократите, които не харесват този похват. Николай Ненчев така и не набра инерция, която да му даде видимост. Волен Сидеров е в ролята на Уди от „Играта на играчките“ – захвърлен настрани, защото вече не е интересен заради по-новите модели на Баз светлинна година, каквито са Костадинов, Радостин Василев и Ивелин Михайлов. Не виждам перспективи и при червените кандидатури, например на проф. Александър Томов и Георги Димов, при положение че този вот ще се концентрира в Йотова.

Разбира се, всичко казано дотук е поне до известна степен гледане на кафе и гадаене на боб, макар и в рамките на политологичния анализ.

Клишето в случая е вярно – само хората могат да изберат какво искат за държавата си. Вариантите в крайна сметка са два. 

Първият, който може да се осъществи с избора на Илияна Йотова, е пълна концентрация на властта в кръга около „Прогресивна България“, която де факто зае мястото на залязлата БСП. Това ще постави България в ситуация, в която тя никога не е била в демократичната си история – в разгара на Виденовата зима Петър Стоянов беше избран за президент, а по време на тройната коалиция Станишев нямаше абсолютно мнозинство в парламента. Ако този вариант се осъществи, стабилността му много ще зависи от това дали от „Прогресивна България“ имат капацитета да управляват успешно – нещо, в което след първата си половин година във властта не успяват да убедят.

Вторият вариант е да имаш авариен бутон. Ако нещо се обърка, например ако неуспешната финансова политика доведе до нови масови протести, хората да имат съюзник в Президентството. Подусловието обаче е дали този съюзник да е популист – позицията, на която навремето Жорж Ганчев не успя да се изкачи, или системен демократичен играч, отказващ да зачеркне всичко постигнато през последните десетилетия, какъвто, изглежда, е Андрей Гюров.

Intel Moves Forward at Ohio One With First Major Structural Truss Installation Arizona Fab 62 Tooling

Post Syndicated from Vic A original https://www.servethehome.com/intel-moves-forward-at-ohio-one-with-first-major-structural-truss-installation/

Intel Ohio One is making progress with truss installation as part of its construction and future wafer capacity

The post Intel Moves Forward at Ohio One With First Major Structural Truss Installation Arizona Fab 62 Tooling appeared first on ServeTheHome.

Upstreaming Tyr: Rust, DRM, and the Linux Kernel (Collabora)

Post Syndicated from corbet original https://lwn.net/Articles/1102024/

The Collabora blog provides
an update on Tyr
, a driver for Arm Mali GPUs.

One of our biggest challenges has been developing Tyr while the
Rust kernel abstractions and driver interfaces are also being
developed. As the driver interfaces are naturally revised and
improved, we have rewritten Tyr several times to adapt to the
larger Rust ecosystem. This not only makes progress much slower
than it would be with a mature API, but also stalls progress for
capabilities, such as job scheduling, while the abstraction is
properly designed, reviewed, tested, and merged upstream.

But working in this evolving environment is also precisely where
Tyr is able to provide the most value. As a user of these new Rust
abstractions, Tyr helps to expose their requirements and
limitations.

[$] Understanding Nix flakes

Post Syndicated from jzb original https://lwn.net/Articles/1094226/

Nix flakes are an
experimental feature of the Nix package-management
tool
designed to build projects in a more self-contained and reproducible
way. Despite the feature’s experimental status, it has become increasingly
popular for open-source projects to publish flake.nix files that offer
predefined development environments and build automation even when those
repositories may not offer an upstream package or module for the NixOS Linux distribution. Although
Nix flakes have a complicated history, and the path for stabilization is
uncertain, flakes can provide useful capabilities for projects that choose to
include them.

Introducing full transaction detection for Cloudflare WAF

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/full-transaction-waf/

Today, we are expanding our web application firewall (WAF) by adding two new capabilities: full transaction detections and response rules. Full transaction detections evaluate each HTTP request alongside its response to identify evidence of exploitation. It helps answer both "Does this request look malicious?" and "What happened when the application handled it?" Response rules can then block the origin’s response before it reaches the requester.

These are valuable protections because the latest frontier models are uncovering vulnerabilities buried deep in widely used software, giving defenders clarity on what to fix — and attackers new paths to exploit. The recent php2shell vulnerability shows the stakes: a flaw in a common software component can put applications across the Internet at risk. AI agents scanning for vulnerabilities can be extremely persistent, adapting payloads using feedback, and chaining vulnerabilities, credentials, and permissions. An application's response can reveal whether an attempt worked and give an attacker information that helps them go deeper.

Inspecting incoming requests remains essential for stopping recognizable attacks before they reach an application. But some threats become clear only when the request is considered alongside what the origin returns. A suspicious input followed by a response exposing sensitive information tells a different story from the same input followed by a rejection or an error.

With these new capabilities, customers can use Cloudflare-managed protections or build their own policies combining request and response properties. This extends our always-on application security framework, with detection results available in Security Analytics to support investigation. Our first managed protections using this capability address the recently disclosed php2shell vulnerability.

And the best part? We are making these new capabilities generally available to all Cloudflare customers, including Free plans.

Request inspection is not enough

Cloudflare WAF protects websites and APIs with managed rules, custom rules, and rate limiting. Managed rules provide protection for known attack techniques and vulnerabilities while custom rules let teams create their own policies using parameters such as an IP address, URL path, headers, and request body. These controls operate at the request level to stop exploits or unwanted traffic from reaching the origin.

For many threats, this is the right place to act. However, treating every suspicious request as a confirmed exploit creates a difficult choice. Broad request signatures can catch more potential attacks, but they can also show “false positives”, such as matching legitimate traffic — which then breaks the applications. Deploying only rules that do not trigger false positives reduces that risk, but can leave more room for more ambiguous traffic to reach the server.

The response provides the missing evidence. Cloudflare can now correlate it with the request that produced it, so detections can account for the outcome of the entire HTTP transaction.

As an illustrative example, consider an application that lets users download files. An attacker manipulates the file parameter to request a private configuration file outside the permitted directory:

GET /download?file=../../config/database.ini

Request inspection can recognize this path traversal attempt and block it before it reaches the application. The request alone, however, cannot establish whether the application would expose the file. It might reject the request, ignore the traversal, or return an error. If the request reaches the origin, a response like this provides additional evidence:

200 OK
Content-Type: text/plain
[database]
username=app_service
password=EXAMPLE_SECRET

Full transaction detection provides a missing piece: it can correlate the attempted file access with response content characteristic of a private configuration file. Configuration-like text can legitimately appear in documentation or example downloads; combining it with a traversal attempt provides stronger evidence of sensitive data exposure than either signal alone. A response rule can then replace the origin response with a Cloudflare WAF block page and HTTP 403 before it reaches the requester, effectively blocking the exploit by preventing sensitive information from reaching the attacker.

Detection and mitigation are separate by design

Full transaction detection extends the always-on detection framework we introduced earlier this year. Detections analyze traffic and attach metadata to the request and response, rules then decide what to do with those results.

Separating those jobs gives customers visibility before they design a policy. Security teams can inspect detections in their own traffic, understand which endpoints and signatures are involved, and choose the response that fits their application. Similar to the approach for the request-based Attack Signature Detection, the outcome of the detections are stored in fields that can be accessed in the response custom rules or used in managed detections to block traffic.

Mirroring the request detection fields, the following new fields are added to our platform:

Field

Description

cf.waf.signature.response.confidence

Confidence values associated with matching signatures

cf.waf.signature.response.categories

Categories associated with matching signatures

cf.waf.signature.response.ref

Signature reference IDs, up to 10

The first full transaction detections focus on exploit confirmation for high profile vulnerability. It correlates suspicious input with response signals that indicate an exploit may have succeeded.

We will expand coverage over time by supporting other use cases, including detecting data exposure and exfiltration signals. This is important for the Internet beyond any one application: defenses can distinguish probing from evidence of impact, while detection of exposed data and services can reach customers that do not have a dedicated security team tuning every WAF rule.

Create rules on the response

Detecting evidence of exploitation is most useful if you can act on it in real time. Response custom rules turn full transaction detections into inline protection by blocking a matching origin response before it reaches the requester, although it cannot undo actions already performed at the origin.

Security teams can now combine request and response properties with detection results to decide which responses to block. When a blocking rule matches, Cloudflare replaces the origin response with a WAF block page or a custom response.

Response phase controls are available in the Cloudflare dashboard at the bottom of the Security > Security Rules page, with both managed protections and custom rules.

We have released both managed and custom rules to all plans, including Free plans. Over time, we will follow the same approach we use for request detections, where managed detections for free plans focus on high-profile vulnerabilities, while paying customers get a richer catalog of detections.

Managed detections

All customers get the protection of the full array of transaction detections through the Cloudflare Managed Response Firewall Default ruleset, which is designed for a simple one-click deploy and simplified configurability. When a signature matches, the managed detection will block the response and return a standard WAF block page.

You can edit the Cloudflare Managed Response Firewall Default scope to run detections only on a portion of their applications, for example by excluding or restricting the detection to a specific path. Paying customers can use detection fields in custom response rules to create more tailored policies.

Custom rules

Custom response rules are designed to give customers full control of the rule logic. A useful rule can stop an administration interface from being exposed when an authentication gateway has not marked the request as internal. For example:

http.request.uri.path starts_with "/admin" and not http.request.headers["x-internal-user"][0] eq "true" and http.response.code eq 200 and http.response.headers["content-type"][0] contains "text/html"

This blocks only when an unauthenticated request targets `/admin` and the origin actually returns a successful HTML administration page. It does not block ordinary authentication failures, redirects, or non-administration traffic.

All customers can create up to three custom response rules supporting Log and Block actions. The fields and functions available in response to custom rules mirrors what your plan gives you access to in request custom rules already. Creating rules on the response body is not yet available.

Following the Attack Signature Detection approach, paying customers also have access to the outcome of attack detections through the cf.waf.signature.response.*  fields listed above. These fields can be combined with other parameters (such as a hostname, URL path, source IP, request header) to enable protection on a single path, or limit the policy to application-specific context. We are currently rolling out the response fields to all our accounts. If you don’t have access to them yet, please contact your account team.

Investigating matching requests

When a managed or custom response rule logs or blocks a transaction, the event is available in Security Events. This means responders can trace any detection back to the full context of the request and the specific rule that took action.

At the moment, both request-only rules and full-transaction rules are shown together in the same analytics page. In Security Events, the events generated by response rules are part of the Managed Rules or Custom Rules service. You can filter events belonging to a specific rule ID in the relative rule list section.

Get started today

Full transaction detection is generally available for all zones proxying traffic through Cloudflare. To verify that you’re protected, go to Security > Security Rules in the Cloudflare dashboard. If you want to customize your policy, start by reviewing full transaction detections in Security Analytics, then create the response phase policy that fits your application.

Cloudflare deploys protections against php2shell vulnerability

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/php-vulnerabilities-waf-protection/

Today, Calif.io, Wiz, OpenAI and Quarkslab disclosed two vulnerabilities in PHP, tracked as CVE-2026-109618 and CVE-2026-109619 and known as php2shell. The vulnerabilities affect all web servers running PHP 5.4 or later and they may allow an attacker to cause denial of service, remote code execution, and data exposure when an application processes specially crafted HTTP traffic.

Cloudflare has been part of a coordinated effort to deploy mitigations to protect the Internet, working with PHP foundation, OpenAI and Wiz among others. Cloudflare has developed and deployed web application firewall (WAF) protections since early October 2026, which were deployed about 9 hours ahead of public disclosure. Starting on October 21 3:02 am UTC, Cloudflare customers using our free or paid WAF were protected by default against php2shell.

Cloudflare successfully deployed multiple mitigations for all its customers while the vulnerability was leaked before the official release date and we observed attack traffic targeting our customers. We observed how attackers were mutating the attack payload to try to bypass our protections by tracking the volume of matches and cross-referencing with the rule logic.

Protecting against php2shell required more than standard request-based rules. Request data alone does not always provide enough evidence to distinguish an exploit from legitimate traffic. The origin’s response adds context, helping identify whether an exploit succeeded while reducing the risk of false positives.

To deliver this protection, we developed full transaction detection, a new Cloudflare WAF capability that combines signals from the request and response within the same HTTP transaction. Response rules can then block a matching origin response before it reaches the requester. The php2shell protections are the first managed detections we have released using this capability.

Customers should patch their PHP repos even with WAF protections providing an additional layer of defense-in-depth mitigation. Our security analysts continue monitoring attack activity and update the rules when and if new techniques and variations emerge in the hours and days ahead. You can track new rules in the changelog.

The protections are available and deployed automatically on all plans with WAF deployed, including Free users.

What we know about the vulnerabilities

PHP is used by almost 70% of websites. The php2shell vulnerabilities affect the PHP runtime itself and can allow attackers to execute malicious code on vulnerable servers, expose customer data, or disrupt services. Because PHP underpins widely used platforms such as WordPress and Magento, these flaws could potentially affect a large number of applications across the Internet.

The two vulnerabilities involve how PHP handles memory when something goes wrong while processing a HTTP request. Normally, PHP allocates memory to store the data it needs to process a request, then releases it when that work finishes. If processing stops unexpectedly, for example because it runs out of memory, PHP fails to clean up the memory safely. These vulnerabilities arise when PHP handles an error and then tries to use data that was not fully set up or memory that has already been released.

An attacker can send specially crafted HTTP requests to trigger these conditions. Large requests are one way to put memory under pressure, but the problem goes beyond consuming server resources. By manipulating the data PHP encounters in this invalid memory, an attacker may be able to crash a PHP process, expose sensitive information, or execute code provided by the attacker.

The two vulnerabilities differ in when the unsafe memory access happens:

Vulnerability

What goes wrong

CVE-2026-109618

PHP runs out of memory and interrupts its work before some internal data has been properly initialized. During cleanup of that request, PHP may use this unfinished data as though it were valid.

CVE-2026-109619

A fatal error interrupts a request, leaving PHP holding references to memory that is released when the request ends. When the same PHP process handles a later request, it may follow those outdated references and access memory that is no longer valid and expose sensitive data.

These flaws are in the PHP runtime, so updating website code or a plugin(s) alone does not fix these vulnerabilities. Administrators need to update the PHP software running their applications. If a hosting provider manages PHP, ask the provider to apply the security update.

Administrators can follow the PHP advisory for affected versions and remediation instructions. Keep Cloudflare WAF protections enabled while patching. Restricting unnecessary uploads and limiting upload sizes can also reduce exposure, but these measures do not replace the PHP fix.

New rules

For Free customers, new rules have been released under the Cloudflare Managed Free Ruleset (Ruleset ID 77454fe2d30c4220b5701f6fdfb893ba). Free customers don’t have to take any actions to enable the protection. To override the ruleset behavior you can refer to our documentation.

Rule Description

Rule ID

Generic Rules – Anomalous Execution – 1

4e315666e8e344cdb64119a3b5ccf32f

Generic Rules – Anomalous Execution – 2

00c10e6cc4da4bd08722adeebcd95984

Generic Rules – Anomalous Execution – 3

48ddf592361e4fdb97a8a85982dab691

Generic Rules – Anomalous Execution – 4

3556683d512a47f2937899c524b1a4c6

Generic Rules – Anomalous Execution – 5

da07c85852e34625bb478496302ede46

Generic Rules – Anomalous Execution – 6

19373a83abb840e18ab3ce5a7975ce1b

Generic Rules – Anomalous Execution – 7

07f0b6ddaabf40b1b2042dade8d613fa

Protection for paid plans has been released as part of the Cloudflare Managed Ruleset (Ruleset ID efb7b8c949ac4650a09736fc376e9aee). If you are on a Professional, Business, or Enterprise plan, review your Managed Ruleset deployment to confirm it’s deployed block mode.

Rule Description

Rule ID

Generic Rules – Anomalous Execution – 1

c1d409ad838f47f59446f21cc438d5dd

Generic Rules – Anomalous Execution – 2

f9a45927414245e3a64bb12d0a0c2f64

Generic Rules – Anomalous Execution – 3

771c654ae1154d4daa72f4e1545d163c

Generic Rules – Anomalous Execution – 4

217005865f0145f392300bac212afcc9

Generic Rules – Anomalous Execution – 5

38efdb17ea594501bb55a1d71867b12e

Generic Rules – Anomalous Execution – 6

4148ae686fdb4d01be673fab9d9c073d

Generic Rules – Anomalous Execution – 7

1389aa259617437392ce149c48143645

To better identify exploit attempts, Cloudflare developed full transaction detection, a new WAF capability that analyzes both sides of the same HTTP transaction. While some malicious payloads can be identified using the request alone, the response contains useful signals that can be used to create rules with higher confidence, reducing false positives. A matching full transaction rule can block the origin response before it reaches the requester. Learn how it works in our full transaction detection blog post.

The following rules have been deployed to the new Cloudflare Managed Response Firewall Default for customers on all plans, including Free:

Rule Description

Rule ID

Default block for High confidence Signatures

afffe22785674c80a31875c848d2242a

Note: rule descriptions will be updated soon.

Review events and customize protection

To analyze blocked requests, visit Security > Security Analytics > Events. Filter by the rule IDs in the table above and inspect the matched request, action, and path. Events identify whether the action came from a managed or custom rule. Customers who need to tailor the protection can update the scope of the Managed Ruleset to the parts of an application where it is relevant.

Update PHP and keep the protection enabled

Cloudflare customers using our Managed Ruleset are protected by default. We recommend following the advisory recommendation and applying the vendor update to your PHP repos as soon as possible while keeping the WAF protection enabled as an additional protection. Our WAF analysts will continue to update protections as new techniques emerge.

PHP patches released for two critical RCEs

Post Syndicated from jzb original https://lwn.net/Articles/1102014/

The PHP project has published PHP
versions 8.5.12,
8.4.27, 8.3.36 and 8.2.35 to address
two critical vulnerabilities that could allow unauthenticated remote code
execution.

Who is at risk: all PHP installations serving web requests,
including PHP-FPM, Apache with mod_php, php-cgi, FrankenPHP and LiteSpeed. We
consider the risk highest for mod_php, with a demonstrated exploit where an
unauthenticated request can trigger the attack before any application code
runs.

The vulnerabilities:

  • RCE via OOM corruption, CVE-2026-109618 (GHSA-w8hw-w9fx-j79w): out-of-memory
    handling can interrupt PHP while internal request data is only partially initialized. Request cleanup may then treat the invalid data as valid.
  • RCE via stale global state, CVE-2026-109619 (GHSA-6wmf-4rv5-p3rp): request-owned
    internal state can survive after its backing memory has been freed. A later
    request handled by the same worker may use that stale state before normal
    initialization resets it.

PHP versions older than 8.1 will not receive updates from the project, though
the project has provided some patches for PHP
7.4
, PHP
8.0
, and PHP
8.1
to assist in creating backports. According to the
announcement, Linux distributions and vendors received patches in advance, so
updated packages should be coming soon.

The collective thoughts of the interwebz