Post Syndicated from xkcd.com original https://xkcd.com/3294/
Post Syndicated from xkcd.com original https://xkcd.com/3294/
Post Syndicated from Oscar Diaz original https://aws.amazon.com/blogs/security/incident-response-guide-for-aws-cloudtrail-investigations-part-2/
In Part 1 of this guide, we examined two common incident scenarios: cross-account Amazon Simple Storage Service (Amazon S3) data deletion with ransomware implications, and cryptocurrency mining deployed through AWS CloudFormation using exposed AWS Management Console credentials. We also introduced key incident response terminology and investigative frameworks for analyzing AWS CloudTrail events.
In this second part, we explore a more complex, multi-stage attack: how a web application vulnerability can cascade into credential harvesting and unauthorized access to Amazon Bedrock services across multiple AWS Regions. We also cover additional investigation techniques and hardening steps to strengthen your security posture.
This scenario examines how a web application vulnerability can cascade into a multi-Region event targeting Amazon Bedrock services. The investigation demonstrates how threat actors chain together multiple techniques, using Amazon Elastic Compute Cloud (Amazon EC2) Instance Metadata Service version 1 (IMDSv1) through server-side request forgery (SSRF) and cross-Region pivoting to access Amazon Bedrock.
Your security team receives multiple alerts: failed AWS Identity and Access Management (IAM) operations in the us-east-1 Region, successful console sign-ins without multi-factor authentication (MFA), and unusual Amazon Bedrock API calls from us-east-2. Initially, these might seem like unrelated events across different services and Regions. However, as our Security Incident Response Team (SIRT) discovered, they represent a carefully orchestrated event chain that began with a web application vulnerability and culminated in unauthorized access to your organization’s AI infrastructure.
The architecture in figure 1 maps a multi-stage attack that exploits the trust relationship between Amazon Elastic Compute Cloud (Amazon EC2) instances and AWS services. A threat actor identified a server-side request forgery (SSRF) vulnerability in a web application running on an EC2 instance that had an attached webdev IAM role. Rather than attempting to escalate privileges directly, the threat actor used this foothold to reach the Instance Metadata Service version 1 (IMDSv1) endpoint and retrieve the temporary credentials issued to the webdev role. Because IMDSv1 returns credentials in response to a basic request with no session token, an SSRF flaw is enough to harvest them, which is why these credentials became the pivot point for everything that followed. The attack unfolded in five stages. Each stage is numbered in figure 1 so you can follow the progression from the initial web request through to the cross-Region Amazon Bedrock activity:
webdev role.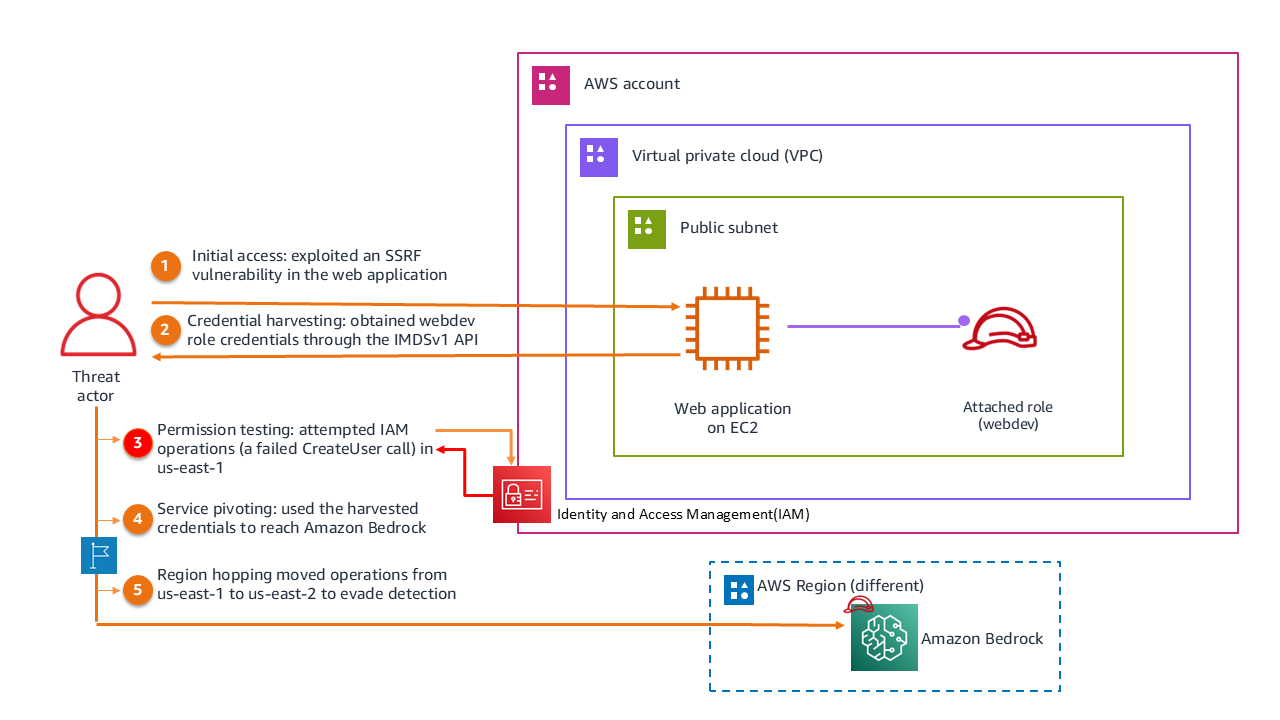
Figure 1: Scenario 3 architecture
In this section, we walk through the CloudTrail evidence that documents the attack from start to finish. Each of the four events that follow maps to one or more stages in the progression described previously, and together they trace how the threat actor moved from harvested credentials to active misuse of Amazon Bedrock. For each event, we present the relevant portion of the CloudTrail log record, highlight the fields that matter most for the investigation, and include a forensic legend that explains what each highlighted field reveals.
We cover the following events:
CreateUser call in us-east-1 that reveals the compromised role and the IMDSv1 credential source.ListFoundationModels call in us-east-2 that marks the Region hop and the shift to AI services.Converse call that invokes the Amazon Nova Pro model, confirming unauthorized usage.As you read each event, focus on how the fields connect one stage to the next. The same webdev role, the same source IP address, and the recurring ec2RoleDelivery value are the threads that tie these otherwise separate events into a single attack chain.
Event 1: Permission boundary testing (15:53:49 UTC): The first suspicious activity appeared as a failed CreateUser API call in us-east-1. The CloudTrail log records an AssumedRole session attempting to create an IAM user named adm1n but receiving an AccessDenied error. The webdev role is visible in the userIdentity field, readOnly is false (indicating a write operation attempt), and the user-agent shows AWS Command Line Interface (AWS CLI) on Windows, suggesting programmatic access from the harvested credentials.
Event 2: Console access establishment (15:59:29 UTC): Six minutes later, the threat actor successfully signed in to the AWS Management Console using the same credentials. The ConsoleLogin event records that MFA wasn’t used (MFAUsed: No), and the source IP (75.3.231.105) provides attribution data. The user agent indicates Chrome browser on Windows 10.
Event 3: Amazon Bedrock service reconnaissance (17:20:00 UTC): Nearly two hours later, the threat actor pivoted to Amazon Bedrock, making a ListFoundationModels API call in us-east-2. This event exhibits several patterns: a Region change from us-east-1 to us-east-2 (potential defense evasion), a shift from IAM to AI services, readOnly: true (reconnaissance rather than modification), and sessionCredentialFromConsole: “true”, which ties the call to the console session established in Event 2 rather than a fresh IMDSv1 credential retrieval.
Event 4: Active model exploitation (17:25:48 UTC): Five minutes after the reconnaissance call, the threat actor moved from enumeration to active exploitation, invoking the Amazon Nova Pro model through the Converse API in us-east-2. The additionalEventData field quantifies the unauthorized usage at 944 input tokens and 126 output tokens, confirming that the threat actor successfully prompted the model and received a response.
As you review the event logs, a handful of fields do most of the investigative work in this scenario. Understanding what each one reveals, and why it matters, is what turns a collection of individual log records into a coherent attack narrative.
The userIdentity field is the starting point for attribution. In this scenario it carries the EC2 instance ID as the session name, which is what let us trace the harvested credentials back to a specific compromised instance rather than a human user. Whenever you see an assumed-role session, this field answers the first question of any investigation: whose credentials are these, and where did they come from?
The readOnly field reveals the intent behind an action. A value of true marks reconnaissance, such as the ListFoundationModels call the threat actor used to enumerate available models, while false marks an attempt to change or use something, such as the CreateUser call or the Converse invocation. Sorting events by this field quickly separates the threat actor’s information gathering from the actions that caused actual impact.
The awsRegion field is easy to overlook, but in this scenario it exposed the threat actor’s evasion strategy. The shift from us-east-1 to us-east-2 wasn’t incidental; threat actors move between Regions because monitoring, alerting, and access controls are often configured inconsistently across them. Watching this field helps you spot activity that has deliberately moved away from where your detection is strongest.
Finally, the userIdentity.invokedBy field identifies when an AWS service, rather than a user or a set of harvested credentials, made the request on your behalf. CloudTrail populates it only when the caller is an AWS service, such as through a service-linked role, a service role, or a forward access session. It doesn’t appear in the events for this scenario because the threat actor called Amazon Bedrock directly with the harvested webdev credentials. That absence is itself informative: it confirms the requests came from a principal acting on its own rather than from a legitimate service-driven workflow. As agent-based and service-integrated Amazon Bedrock workloads become more common, checking this field separates expected service activity from credentials driven directly by a threat actor.
With the full attack chain mapped, from SSRF through credential harvesting to Amazon Bedrock service misuse, the investigation turned to a harder question: what did each stage actually cost us, and what would stop it from happening again? A few priorities shaped that work.
The first was figuring out where the credentials came from and how far the exposure reached. It was clear the threat actor had valid credentials for the webdev role, but the more useful question was why a web application role could reach Amazon Bedrock at all. The customer confirmed there was no business reason for it, so we needed to understand whether that permission was a deliberate misconfiguration or an oversight, and then look for other EC2 instances carrying the same role attachment. One compromised instance is an incident; a fleet of instances with the same over-scoped role is a much bigger problem waiting to happen.
Next, we wanted to know what the threat actor did after they got into Amazon Bedrock. Reconnaissance and active use carry very different consequences, so we traced which foundation models were touched and whether any were actually invoked or only enumerated. That distinction matters for scoping the damage, and it signals whether data exfiltration is a concern. Unusual model usage, unexpected prompt volume, or output patterns that don’t match any legitimate workload are the signals that reconnaissance has turned into something worse.
The Region hop was its own line of inquiry. The move from us-east-1 to us-east-2 was almost certainly deliberate, and the investigation focused on understanding what the threat actor gained by it. In practice, that meant comparing the two Regions: were the monitoring and access controls in us-east-2 weaker than in us-east-1, and what else did the threat actor reach in the secondary Region once they were there? Inconsistent controls across Regions are one of the most common ways activity slips past detection.
Tying it all together was the timeline, which shows how quickly the threat actor moved through the chain:
Converse call) (us-east-2)Following the credentials across those events fills in the rest of the story. IMDSv1 handed the threat actor temporary credentials for the webdev role, and the same role appears in every event that followed, which confirms the credentials were reused rather than replaced. Nowhere in that sequence was MFA required, and that single gap is what let one harvested credential stay useful across two hours, two Regions, and two very different services.
The following checklist captures the actions needed to contain the incident, remediate the vulnerability, and assess the scope of unauthorized AI service usage. Each item names where to look and what a finding looks like, so the checklist stays usable under the time pressure of a live incident.
http://169.254.169.254.aws ec2 modify-instance-metadata-options --http-tokens required --http-put-response-hop-limit 1. Setting --http-tokens required means credentials are only returned when the caller presents a session token it obtained through a PUT request, which a basic SSRF cannot do. Setting the hop limit to 1 keeps the metadata response on the instance itself, so a request coming from a container or proxy an extra hop away never receives it.webdev role could reach by reviewing its IAM policy and any resource-based policies, so you know the full set of models that were exposed, not only the one that was invoked.webdev role’s session, to confirm what else the same credentials touched.75.3.231.105 to build the network-level picture around each API call.CreateUser, CreateRole, CreateAccessKey, and AttachRolePolicy) that indicate an attempt to establish persistence beyond the temporary credentials. The failed adm1n CreateUser call is the known starting point; confirm nothing similar succeeded.This scenario reveals how a single application vulnerability can cascade into broad unauthorized access when multiple security controls are missing. The following takeaways highlight the key defensive gaps and hardening priorities.
webdev role’s access to Amazon Bedrock across multiple Regions had no business justification for a web application workload, which the customer confirmed during the investigation. Apply least-privilege principles to EC2 instance roles by scoping permissions to only the services and actions the application requires. Use AWS IAM Access Analyzer to identify unused permissions and tighten policies proactively. Overly permissive roles transform a single application vulnerability into broad lateral movement across unrelated services.ec2RoleDelivery: “1.0" field in the logs explicitly confirms the use of IMDSv1, which permits credential retrieval without an authentication token. This architectural weakness makes SSRF-based credential theft trivial, because a web application flaw that can make an outbound request is enough to read the role’s temporary credentials with no further authentication. Transitioning to IMDSv2 mitigates this attack surface by enforcing local, session-based tokens, effectively breaking the threat actor’s exploitation chain. In this scenario, IMDSv2 alone would have stopped the attack at its first step.CreateUser attempt was systematic probing to understand the scope of the harvested credentials, and when IAM actions were denied, the threat actor pivoted to a service the role could actually reach. The combination of programmatic access through the AWS CLI and interactive console access demonstrates the same adaptability. Recognizing this pattern of probe, adapt, and pivot helps responders anticipate the next move instead of reacting to each event in isolation.Beyond the specific attack patterns in this scenario, investigators should be aware of several evasion techniques that threat actors use to confuse defenders and blend into legitimate activity. The top three that we observe across incident response with customers are:
root. The difference is visible in the type field of the userIdentity element of the CloudTrail log record, which indicates the type of user that logged the record.AWSServiceRoleForSupport is a unique IAM role linked directly to AWS Support. Threat actors have created roles with the name AWSServiceRoIeforSupport (note the use of an upper-case letter I instead of a lower-case letter l in Role) in an attempt to trick users into thinking actions taken by this role have been performed by AWS Support.userName field contains the string HIDDEN_DUE_TO_SECURITY_REASONS when the recorded event is a console sign-in failure caused by incorrect user name input. CloudTrail doesn’t record the contents in this case because the text could contain sensitive information. However, threat actors have used this string as an actual username to trick investigators into thinking the name has been obfuscated. This technique is usually associated with a corresponding CreateUser or CreateRole CloudTrail event.CloudTrail event fields help security teams identify identities with unintended access, track threat actor actions, and remediate affected resources. Understanding fields like userIdentity, eventName, and sourceIPAddress improves incident investigation and threat detection. Implementing best practices such as enabling comprehensive logging, using Amazon Athena for analysis, securing logs, and automating responses helps ensure that CloudTrail serves as a robust forensic and incident response tool.
If you suspect unauthorized activity in your AWS environment, AWS Security Incident Response is available to help. The service continuously monitors and triages findings from Amazon GuardDuty and third-party security tools integrated through AWS Security Hub, automatically filtering alerts to surface the most relevant events. In addition to proactive triage, customers can initiate security cases through the service. You can choose to handle these cases internally or receive support from the Security Incident Response Team (SIRT), a dedicated group of security experts available at all times to assist with investigation, containment, and recovery throughout the incident lifecycle.
The following resources provide further guidance on securing your AWS environment and strengthening your investigative capabilities.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Oscar Diaz original https://aws.amazon.com/blogs/security/incident-response-guide-for-aws-cloudtrail-investigations-part-1/
AWS CloudTrail logs contain the evidence you need when investigating suspicious activity in your AWS environment, but knowing which fields matter and how to interpret them can mean the difference between surface-level analysis and uncovering the full scope of an incident. This guide walks you through real-world scenarios, showing you how to analyze CloudTrail events to uncover cross-account unauthorized access, cryptocurrency mining operations, and AI service abuse. You’ll learn the investigative techniques our Security Incident Response Team (SIRT) team uses to handle threats, with practical methodologies you can apply to your own investigations.
Each scenario includes:
Whether you’re in security operations, cloud engineering, compliance, or leadership, this guide provides the investigative mindset needed to move beyond basic CloudTrail queries to comprehensive security analysis.
Throughout this guide, we reference terminology commonly used in incident response and threat intelligence. We’ve provided definitions for key terms to help ensure this guide is accessible to readers from diverse backgrounds, whether you’re in security operations, cloud engineering, compliance, or leadership.
Cross-account access is sometimes necessary in AWS, but misconfiguration creates security risks. In this scenario, your security operations center has received an automated alert that multiple objects have been deleted from the customer-important-data S3 bucket. The initial response seems straightforward: check the CloudTrail logs, identify who deleted the objects, and determine if it was authorized. But as our SIRT team investigated further, what appeared to be a straightforward unauthorized deletion revealed itself as a cross-account incident with ransomware implications. CloudTrail analysis requires recognizing patterns, understanding context, and thinking like a threat actor.
Figure 1 shows the architecture layout for accessing a trusted account and deleting objects from an S3 bucket, which is achieved through the following steps:
CrossAccountS3Access role from a trusted account.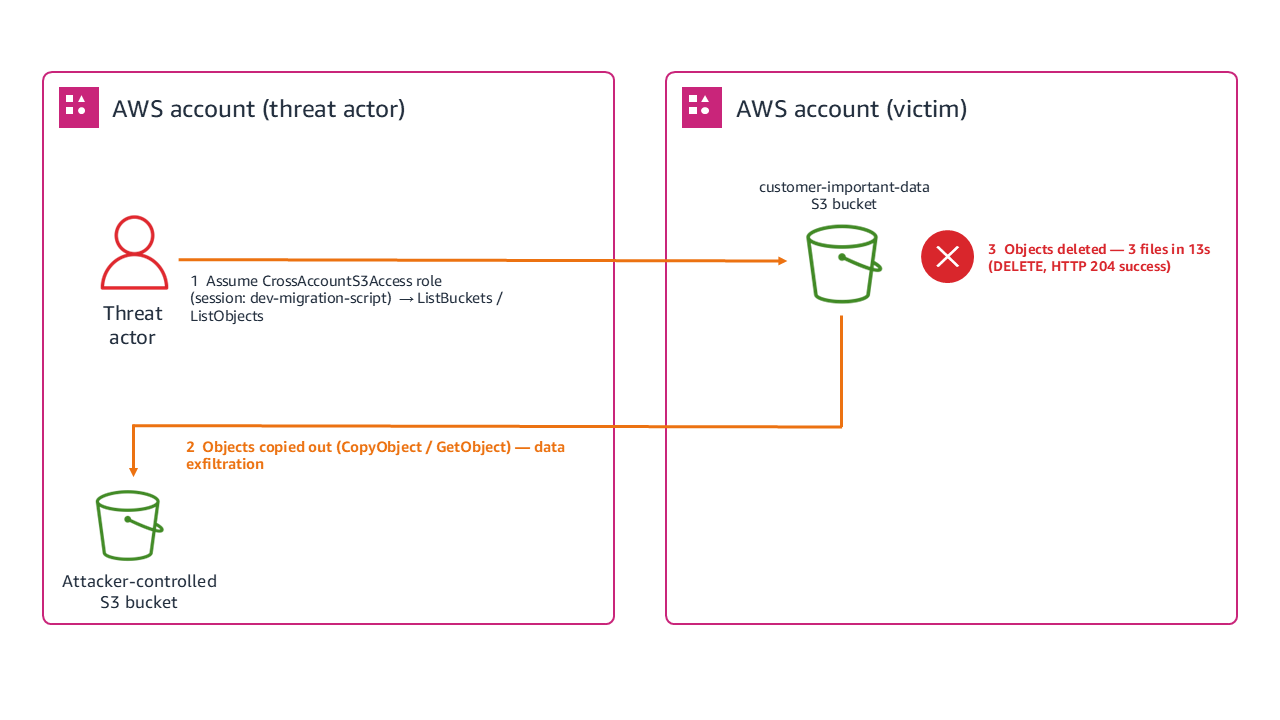
Figure 1: Scenario 1 architecture
Our investigation began with examining the CloudTrail logs, where we discovered that the unauthorized activity started with what many analysts might dismiss as routine activity: a ListBuckets API call made through an assumed role at 14:31:22 UTC. The CloudTrail entry contains a session named dev-migration-script using the CrossAccountS3Access role.
While cross-account access is common in enterprise environments, session names typically reflect legitimate business units. Attackers frequently use masquerading techniques, naming their sessions after common developer tasks or automation scripts, to blend seamlessly into daily operational noise. However, cross-referencing this session name against the external source IP and historical deployment logs confirmed that no such migration project was authorized, signaling a clear evasion attempt by a threat actor and the first indication of unauthorized access. Three seconds later, our logs showed a GET request to list objects in the bucket, which is classic reconnaissance behavior. The threat actor was cataloging available targets, using the same assumed role and IP address. This pattern, which you can see in the arn and eventname in the following log, showed us that the threat actor gathered intelligence, assessed targets, and planned their approach.
After completing their reconnaissance at 14:31:25 UTC, the threat actor went silent for 14 minutes before the first deletion at 14:45:12 UTC. During this window, the threat actor likely reviewed the inventory of objects they’d just enumerated, selected their highest-value targets (financial data, PII, and database backups), and prepared an automated deletion script to execute quickly once ready. We can infer this preparation period based on several factors: no other CloudTrail events from this session appeared during the 14-minute window, the subsequent deletions were precisely timed at 6-7 second intervals suggesting scripted execution, and the targets chosen were the three most business-critical files rather than a bulk delete of everything in the bucket. This selective, scripted approach indicates the threat actor used the reconnaissance data they gathered in the listing phase to build a targeted attack plan before executing it. Within 13 seconds (14:45:12–14:45:25 UTC), the threat actor deleted three files from the customer-important-data bucket: a financial report (q4-2024.xlsx at 14:45:12), a customer personally identifiable information (PII) database (pii-database.csv at 14:45:18), and a production database backup (prod-database-backup.sql at 14:45:25). Each deletion returned an HTTP 204 status code. The Amazon S3 access logs confirm these successful DELETE operations, all originating from the same session.
The 13-second deletion window wasn’t arbitrary. The user-agent string showed AWS Command Line Interface (AWS CLI) usage on Linux, and the precise timing suggested scripted execution rather than manual operations. This indicated preplanned targeting and automated execution to minimize the detection window.
The consistent source IP across events let us search for other suspicious activities from the same source, correlate with threat intelligence feeds, and identify potential lateral movement attempts.
The broad Amazon S3 permissions of the CrossAccountS3Access role raised questions about least privilege implementation, regular access reviews, and the business justification for such extensive cross-account permissions.
With confirmation that misconfigured cross-account access had been taken advantage of to delete data, the next step was to prioritize the investigation. In incident response, priority is driven by three factors: whether the threat actor still has active access (containment urgency), whether sensitive data was exposed or exfiltrated (regulatory and business impact), and whether the attack can spread to other resources or accounts (blast radius). We applied these factors to guide the following questions:
CrossAccountS3Access role? We examined the role’s trust policy and recent modifications, authentication events in both the trusting and trusted accounts, and other sessions using the same role around the same timeframe.GetObject operations on the same objects before the deletions, unusual network traffic patterns during the reconnaissance phase, and CopyObject activities that might indicate data theft.After identifying the scope of the cross-account deletion, the following steps help ensure a thorough response and prevent recurrence.
This scenario illustrates several principles that apply broadly to cross-account incident investigations. Unusual identifiers in session names often reveal threat actor intent or poor operational security. The progression from ListBuckets to targeted deletions shows how threat actors operate with a plan. Cross-account access needs extra scrutiny because trusted relationships become vectors for unauthorized access when credentials are exposed. Understanding why specific files matter helps prioritize response efforts and assess true impact. Precise timing and consistent technical signatures often indicate scripted events that need different response strategies than manual intrusions.
In this scenario, your finance team notices an unexpected spike in AWS costs, particularly around Amazon EC2 compute charges in the us-east-1 AWS Region. During the investigation, we examine how threat actors use legitimate console access to deploy cryptocurrency mining operations through AWS CloudFormation and how investigators can uncover the scope of resource hijacking events. We discover a CloudFormation stack named CRYPTO which you have no record or knowledge of being created. The stack contains EC2 instances running in your production Amazon Virtual Private Cloud (Amazon VPC) consuming significant compute resources, which signals an immediate security investigation.
Figure 2 shows how the threat actor moved from credential acquisition to active mining, following these steps:
CRYPTO in us-east-1.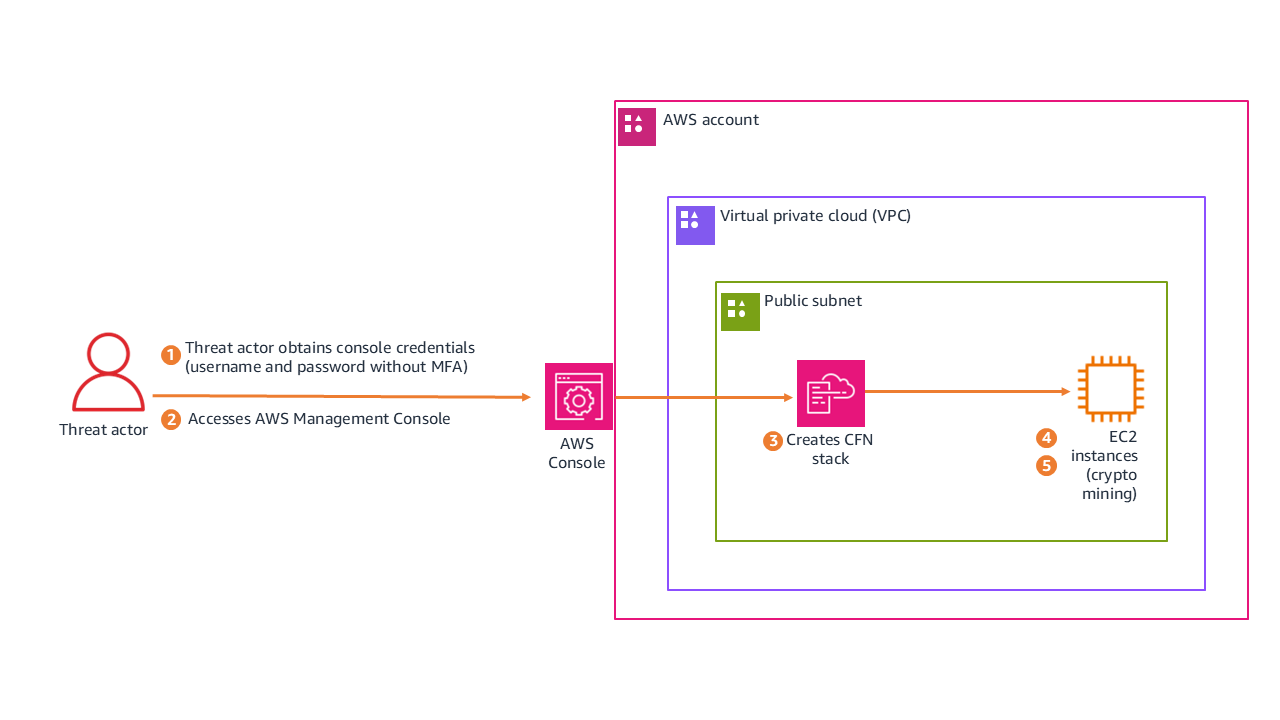
Figure 2: Scenario 3 architecture
The following is the redacted CloudTrail event record for the unauthorized CreateStack action. See if you can use it to find the following information:
The CloudTrail event record includes fields that answer the questions for this scenario.
Stack details summary:
The CloudTrail event confirms the following details about the deployed stack:
CRYPTO is an indicator of cryptocurrency-related activityarn:aws:cloudformation:us-east-1:stack/CRYPTO/2102e190-98a8-11f0-bcea-1209335b107Authentication and session context analysis:
Examining the session metadata reveals how the threat actor authenticated and accessed the environment:
“mfaAuthenticated": “false” indicates that the session was entirely unauthenticated by MFA.“sessionCredentialFromConsole": “true” means that access was funneled through the console.AssumedRole using WSParticipantRole. Session creation occurred at 2025-09-23T18:06:22Z (approximately 50 seconds before stack creation).Advanced forensic insight (the CloudShell pivot)
The sessionCredentialFromConsole: true field is important to note because this access originated from the AWS console rather than external programmatic API keys. Interestingly, while the session originated from the console, the userAgent field reveals the execution environment was exec-env/CloudShell. This shows that the threat actor didn’t manually click through the CloudFormation user interface, instead launching AWS CloudShell on sign-in to execute a prepackaged deployment script. This allowed the threat actor to achieve automated speed while evading traditional static API key monitoring. The mfaAuthenticated: false field represents a security control gap. Particularly in environments handling sensitive data or production workloads, MFA must be enforced for console access.
With the unauthorized stack confirmed, the investigation focused on understanding the full timeline and blast radius. We approached this in three phases, each building on the findings of the previous one.
Reconstruct the console session timeline
The session began at 18:06:22Z and the stack was created at 18:07:12Z, only 50 seconds later. That speed tells us the threat actor came prepared with a script rather than exploring the environment manually. But we needed to know what happened before and after. By filtering CloudTrail for the same session token across the full session duration, we could identify whether the threat actor performed any reconnaissance before deploying the stack, whether they accessed other services or regions during the same session, and whether they attempted to establish persistence (such as creating IAM users or access keys) before or after the mining deployment. Any actions taken outside the CloudFormation deployment could indicate secondary objectives beyond cryptomining.
Examine what the stack actually deployed
The stack name alone doesn’t tell us the full impact. We needed to inspect the CloudFormation template to understand what resources were created and how they were configured. This meant identifying the EC2 instance types (larger instances mean higher costs and potentially more mining output), reviewing the security group rules to determine what network access these instances had to internal resources, checking whether the template included custom AMIs or user data scripts that pulled mining software on boot, and determining if the stack created its own IAM roles with permissions that could be used for further lateral movement. The template itself is evidence. If it was hosted in Amazon S3, the upload event tells us when the threat actor first staged their tools.
Calculate business impact and determine blast radius
Finally, we needed to quantify the damage and determine whether this was isolated or part of a broader compromise. We calculated the total compute cost by multiplying instance hours by instance type pricing, checked whether the mining instances had network paths to production databases or internal services, examined outbound traffic logs for connections to known mining pool IP addresses, and searched for similar stacks or naming patterns across other regions and accounts. The presence of outbound connections to anything other than mining pools would suggest the instances served a dual purpose, potentially exfiltrating data while generating cryptocurrency.
Response checklist
The following checklist captures the key actions needed to contain the incident, assess its impact, and close security gaps.
This scenario highlights how credential hygiene and monitoring controls intersect with resource hijacking threats.
CRYPTO naming suggests either threat actor confidence or poor operational security, both concerning for different reasons.sessionCredentialFromConsole field is your starting point for distinguishing between the two.In this first part, we walked through two real-world scenarios that demonstrate how CloudTrail analysis can reveal the full scope of a security incident. In Scenario 1, we showed how a seemingly routine cross-account role assumption led to targeted data deletion with ransomware implications, and how session names, timing patterns, and source IP correlation help investigators piece together the event chain. In Scenario 2, we examined how stolen console credentials enabled a cryptocurrency mining deployment through CloudShell, highlighting the critical role of MFA enforcement and cost monitoring as security controls. Both scenarios reinforce a core principle: effective CloudTrail investigation goes beyond identifying what happened. It requires understanding how and why, so you can contain the immediate threat and close the gaps that enabled it.
In Part 2 of this guide, we examine how a web application vulnerability can cascade into a multi-Region event targeting AI services, chaining together SSRF, IMDSv1 credential harvesting, and cross-Region pivoting to access Amazon Bedrock. We also cover critical investigation techniques including root user compared to IAM user named root, role name imitation tactics, and the HIDDEN_DUE_TO_SECURITY_REASONS username trick, along with critical hardening steps and additional resources you can use to strengthen your cloud forensic capabilities.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Ken Sanderson original https://blog.cloudflare.com/vulnerability-discovery-remediation/
Your scanner just flagged 4,000 new vulnerabilities, 78 of them critical. Which one do you fix first?
To answer that question, Cloudflare is announcing early access to Vulnerability Discovery and Remediation, now part of Cloudflare Managed Defense. Vulnerability Discovery and Remediation is a new, invitation-only Cloudflare service that helps customers detect and mitigate vulnerabilities in their codebases.
Through the OpenAI Daybreak Defense Network, we use OpenAI Daybreak models, including GPT-5.6 Cyber, for reconnaissance, hunting, and validation against codebases that you authorize us to access. If we detect a vulnerability, we will then propose solutions to you, automatically checking each proposed patch and any accompanying proposed mitigation before presenting them for review. Importantly, you are in the driver’s seat: while we may propose code patches and other mitigations, you decide whether they are implemented.
Choosing what to fix first has always been hard. It's getting harder. Large language models can now surface weaknesses across a codebase in minutes, which means the number of findings keeps climbing. But the real problem is speed. Attackers can use AI to accelerate parts of vulnerability discovery and exploitation, giving security teams and developers less time to decide what matters and act on it.
Imagine that your scanner tells you there's a vulnerability in a handler. It doesn't tell you whether that code is deployed. It doesn't tell you whether anyone is actually hitting that route, what security activity surrounds it, or what controls you already have in place. You have to prioritize the finding without evidence of its production exposure or the protections already in place.
This is where we can help. With our global network, we can see which routes are active, how much traffic they carry, and what security events surround them. When customers enable Vulnerability Discovery and Remediation with Web Application Firewall (WAF), we can also see what rules are already applied and are actively blocking attacks. That context turns a generic finding into a specific priority: this vulnerability is in code that's live, on a route that's heavily used, with recent attack activity and no existing protection. And we can help you mitigate that vulnerability by proposing custom WAF mitigations and code patches tailored to your systems.
If this sounds familiar, it should. In “Build your own vulnerability harness”, we described the model-agnostic pipeline we use to scan Cloudflare's fleet, adversarially validate every finding, and turn raw model output into fixes engineers can trust. That internal system is one pillar of Vulnerability Discovery and Remediation. The harness gave us a way to find bugs at fleet scale. Vulnerability Discovery and Remediation brings that discovery process to the code the customer authorizes us to inspect, then connects the findings to production traffic, security events, and the edge controls that can act on them.
This diagram provides an overview of our process, which we explain in more detail below.
Our solution works across Cloudflare Workers and proxied applications. The process of detecting vulnerabilities begins with the collection of a traffic and security data snapshot from Web Assets and WAF. The snapshot shows which routes are active, how much traffic they receive, and whether recent security events are associated with them. For instance, a path exhibiting a high volume of detection triggers may also be considered critical for security context purposes. Web Assets and WAF itself serve as the first and second pillar of Vulnerability Discovery and Remediation respectively.
Next, we use source code vulnerability analysis to identify potential weaknesses in code. But that analysis does not show which routes reach it, how much traffic those routes receive, whether they receive suspicious requests, or which protections already apply. We treat routes carrying a high volume of requests as hot paths. Source code deployed to these routes undergoes stricter security profiling. Together, these signals provide evidence about how the API is used and where a vulnerability may be exposed.
For Workers, we retrieve the most recent source version of the Worker and its configured routes to identify the endpoints the Worker serves. Next, we match the Worker's routes to Web Assets and request metadata from Workers Observability, tying the exact source under review to the endpoints it handles in production. This collected network context stays available throughout the investigation, allowing agents to pull it when they need it.
Our vulnerability harness then starts up. It begins by using the Reconnaissance agent to map request paths to the parts of the codebase that handle them. Reconnaissance uses that map to send hunter agents into specific sections of the customer-authorized code, where they look for vulnerabilities and pull in relevant network context as needed. That context can help the hunter agents pay more attention to code behind an active or recently targeted route, but it does not establish that a vulnerability exists. Every vulnerability finding has to be corroborated by evidence in the source code.
Once the hunters return their findings, the validation stage checks the proposed mitigations before assigning each vulnerability an initial risk rating based on source code. The network evidence we collect can raise that rating further when, for example, the affected endpoint carries significant traffic or shows signs of active probing.
The result is a prioritized list of findings, each with a recommended code patch and, when the evidence supports it, a Cloudflare WAF Custom rule that can reduce exposure while the code fix is reviewed. If you have authorized our VDR to defend your zone, we will deploy the rules, scoped conservatively around the method, path, and other request details needed to reach the vulnerable code. If a route pattern contains only variables and wildcards, we do not suggest a rule. We would rather miss a possible connection than claim one the evidence cannot support.
The HTTP method override bypass example above shows how these signals work together. The harness maps the source finding to the production route, uses traffic and security activity to prioritize it, and scopes a proposed WAF rule around the requests that can reach the vulnerable code. That rule can reduce exposure while engineering reviews and ships the code patch.
When you authorize an investigation, Vulnerability Discovery and Remediation runs the harness on Cloudflare and sends model prompts from Workers through Cloudflare AI Gateway to OpenAI Daybreak models on OpenAI's servers. GPT-5.6 Cyber is used during reconnaissance, hunting, and validation, and its responses return to the harness so the workflow can continue on Cloudflare. No model inference runs at Cloudflare's edge, and the model cannot apply any patch or rule it proposes.
We keep each investigation narrow by limiting it to the source code and evidence the customer authorizes. Before that context reaches the model, Vulnerability Discovery and Remediation removes what the investigation does not need and applies the redaction controls configured for the engagement. The harness treats source code, logs, and request metadata as evidence to inspect, rather than instructions to follow.
Tool access follows the same boundary: each call is logged and checked against the investigation's access policy before it runs, and every patch or rule proposal must pass checks implemented outside the model. If one of those checks fails, the workflow stops before the proposal reaches customer review.
Nothing is presented for review until it has cleared the checks and our team validates the output. For an edge-defense suggestion, that means validating the rule syntax and running it against synthetic fixtures that represent expected requests, rather than against customer traffic. If a check fails or the result remains ambiguous, we hold the output back and route it for diagnosis.
Passing those checks still does not change your environment. After validation by our team, Vulnerability Discovery and Remediation prepares the source code patch and WAF rule.
Vulnerability Discovery and Remediation is available to selected customers by invitation during early access through our Managed Defense team. Each engagement starts with one application whose codebase the customer authorizes us to investigate. To connect the findings to production, Vulnerability Discovery and Remediation uses authorized read access to the Web Assets operation inventory, the relevant WAF controls, and Workers Trace Events Logpush where available. The investigation is semi-automated, but you review every result before deciding whether to test or deploy a change.
If you're interested in learning more, talk to your Cloudflare account team.
Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/big-data/network-connectivity-patterns-for-the-next-generation-of-amazon-opensearch-serverless/
Network connectivity patterns for private access to Amazon OpenSearch Serverless used to require considerable setup. You had to create virtual private cloud (VPC) endpoints in every consumer VPC and configure Amazon Route 53 Profiles for cross-account DNS. You also had to maintain custom private hosted zones with CNAME records and deploy resolver inbound endpoints for on-premises connectivity. The next generation of OpenSearch Serverless changes this. It uses standard AWS PrivateLink interface endpoints with native private DNS support. Connectivity patterns that previously required multi-step DNS orchestration now work with the same endpoint mechanics you already use for other AWS services.
Collections use resource-based endpoints on the on.aws domain in two formats. The per-collection endpoint (<collectionId>.aoss.<region>.on.aws) reaches a single collection, and the hostname itself identifies which collection you want, so no additional routing information is needed. The per-account Regional endpoint (<accountId>.aoss.<region>.on.aws) reaches any collection in your account through one hostname. Because the hostname alone does not identify a specific collection, you add the x-amz-aoss-collection-name header (or x-amz-aoss-collection-id) to each request to name the target collection. The AWS SDKs include this header automatically when they sign the request with Signature Version 4 (SigV4).
Both formats use standard AWS PrivateLink. You create the VPC endpoint from the Amazon Virtual Private Cloud (Amazon VPC) console or the Amazon Elastic Compute Cloud (Amazon EC2) CreateVpcEndpoint API, using the service name com.amazonaws.<region>.aoss-data. It is the same interface endpoint you create for any other AWS service.
In this post, each pattern shows the architecture, the DNS resolution flow, and the data traffic path. Patterns 1 through 8 operate within a single Region across one or more accounts, labeled Region A in the diagrams, so the repeated Region A boxes in a cross-account pattern are the same Region. Only Pattern 9 spans Regions, shown as Region A and Region B.
These patterns apply to the collection (data) endpoint only. When you create a collection, you also receive an OpenSearch UI endpoint. That endpoint uses a separate PrivateLink mechanism today, with its own VPC endpoint and access policy, and is on a path to move to the standard PrivateLink model. OpenSearch UI connectivity is out of scope for this post.
--generation NEXTGEN.When you create a standard VPC endpoint for com.amazonaws.<region>.aoss-data with private DNS enabled, AWS creates a private hosted zone for *.aoss.<region>.on.aws and associates it with your VPC. This zone maps collection hostnames to the endpoint’s private elastic network interface (ENI) IP addresses. Your compute’s DNS query reaches the VPC’s Amazon Route 53 Resolver at VPC+2, which resolves the hostname to ENI IPs.
One endpoint serves every collection hostname in the Region. The following AWS CLI command creates that interface endpoint, and the --private-dns-enabled flag turns on the private DNS resolution described here.
In Regions that support Federal Information Processing Standards (FIPS), the same endpoint also resolves *.aoss-fips.<region>.on.aws for FIPS-compliant access.
OpenSearch Serverless has no per-collection Dashboards endpoint. Use OpenSearch UI applications to explore and visualize collection data.
The diagrams in the following patterns use an Amazon EC2 instance to represent the compute client. Any compute in the VPC reaches a collection the same way, including EC2 instances, AWS Lambda functions attached to the VPC, and containers on Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS). The connectivity, DNS resolution, and access policies are the same regardless of the compute type.
Compute in a VPC needs private access to collections in the same account. The following diagram shows the architecture for private access from a single VPC.
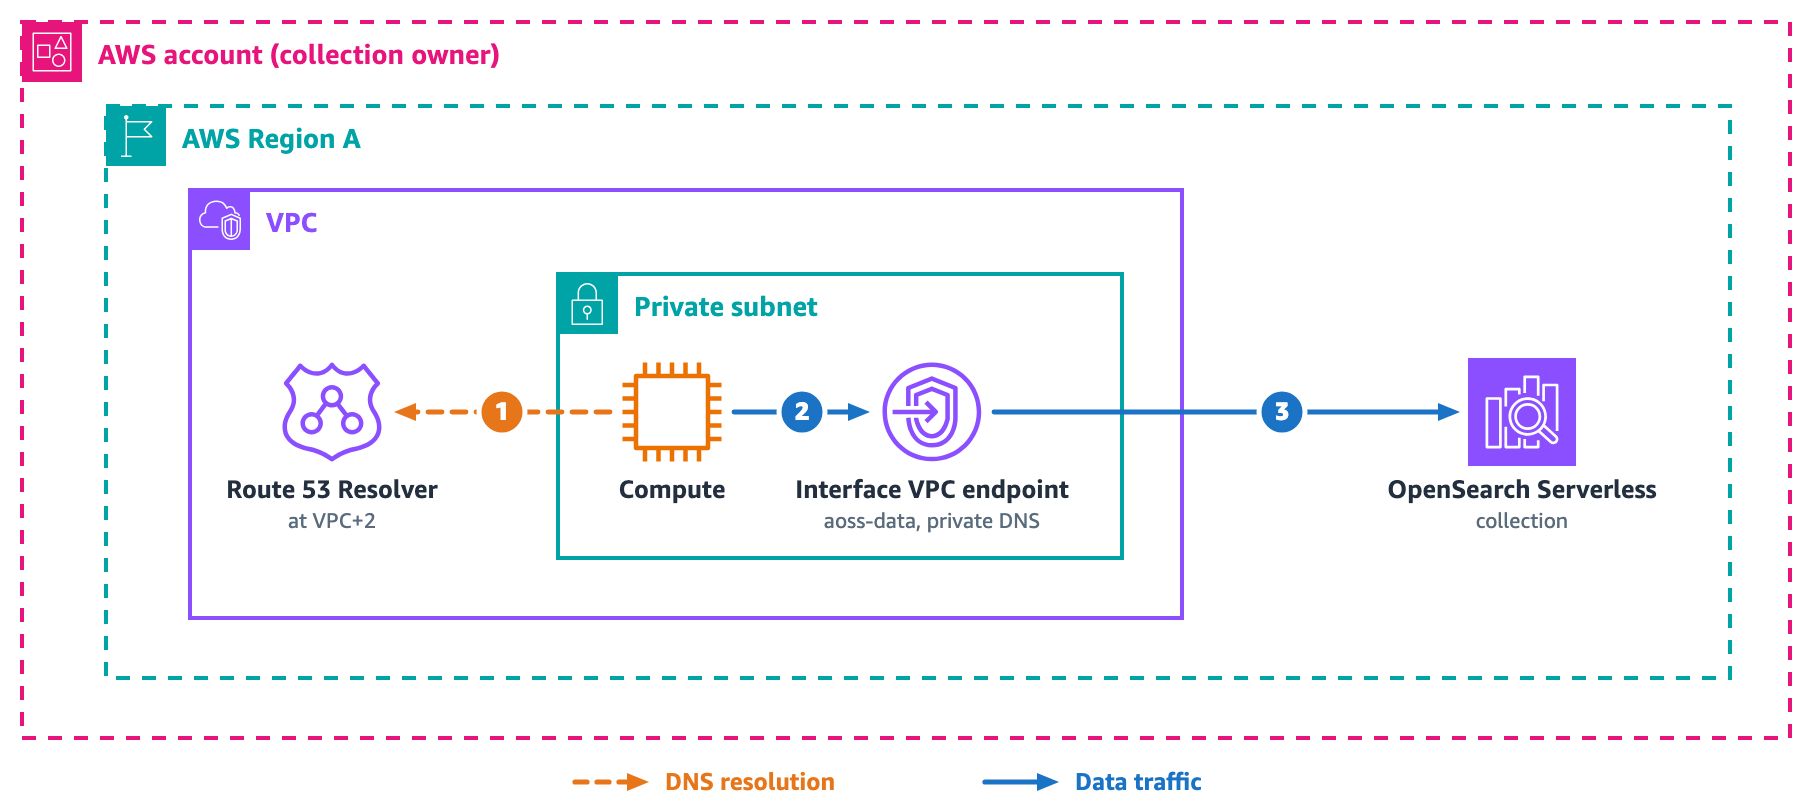
Figure 1: Private access from a single VPC
Create a standard VPC endpoint in the VPC where your compute runs, then reference its ID in the collection’s network policy.
For the DNS resolution flow, (1) compute queries <collectionId>.aoss.<region>.on.aws, and the VPC Route 53 Resolver at VPC+2 returns the endpoint ENI IP addresses because private DNS is enabled on the endpoint.
For the data traffic path, (2) compute connects to the ENI, and (3) PrivateLink forwards the request to the service, which routes to the collection by hostname.
Several VPCs, split by environment, tier, or team, need private access to the same collections. The following diagram shows how each VPC uses its own endpoint to reach the same collections.
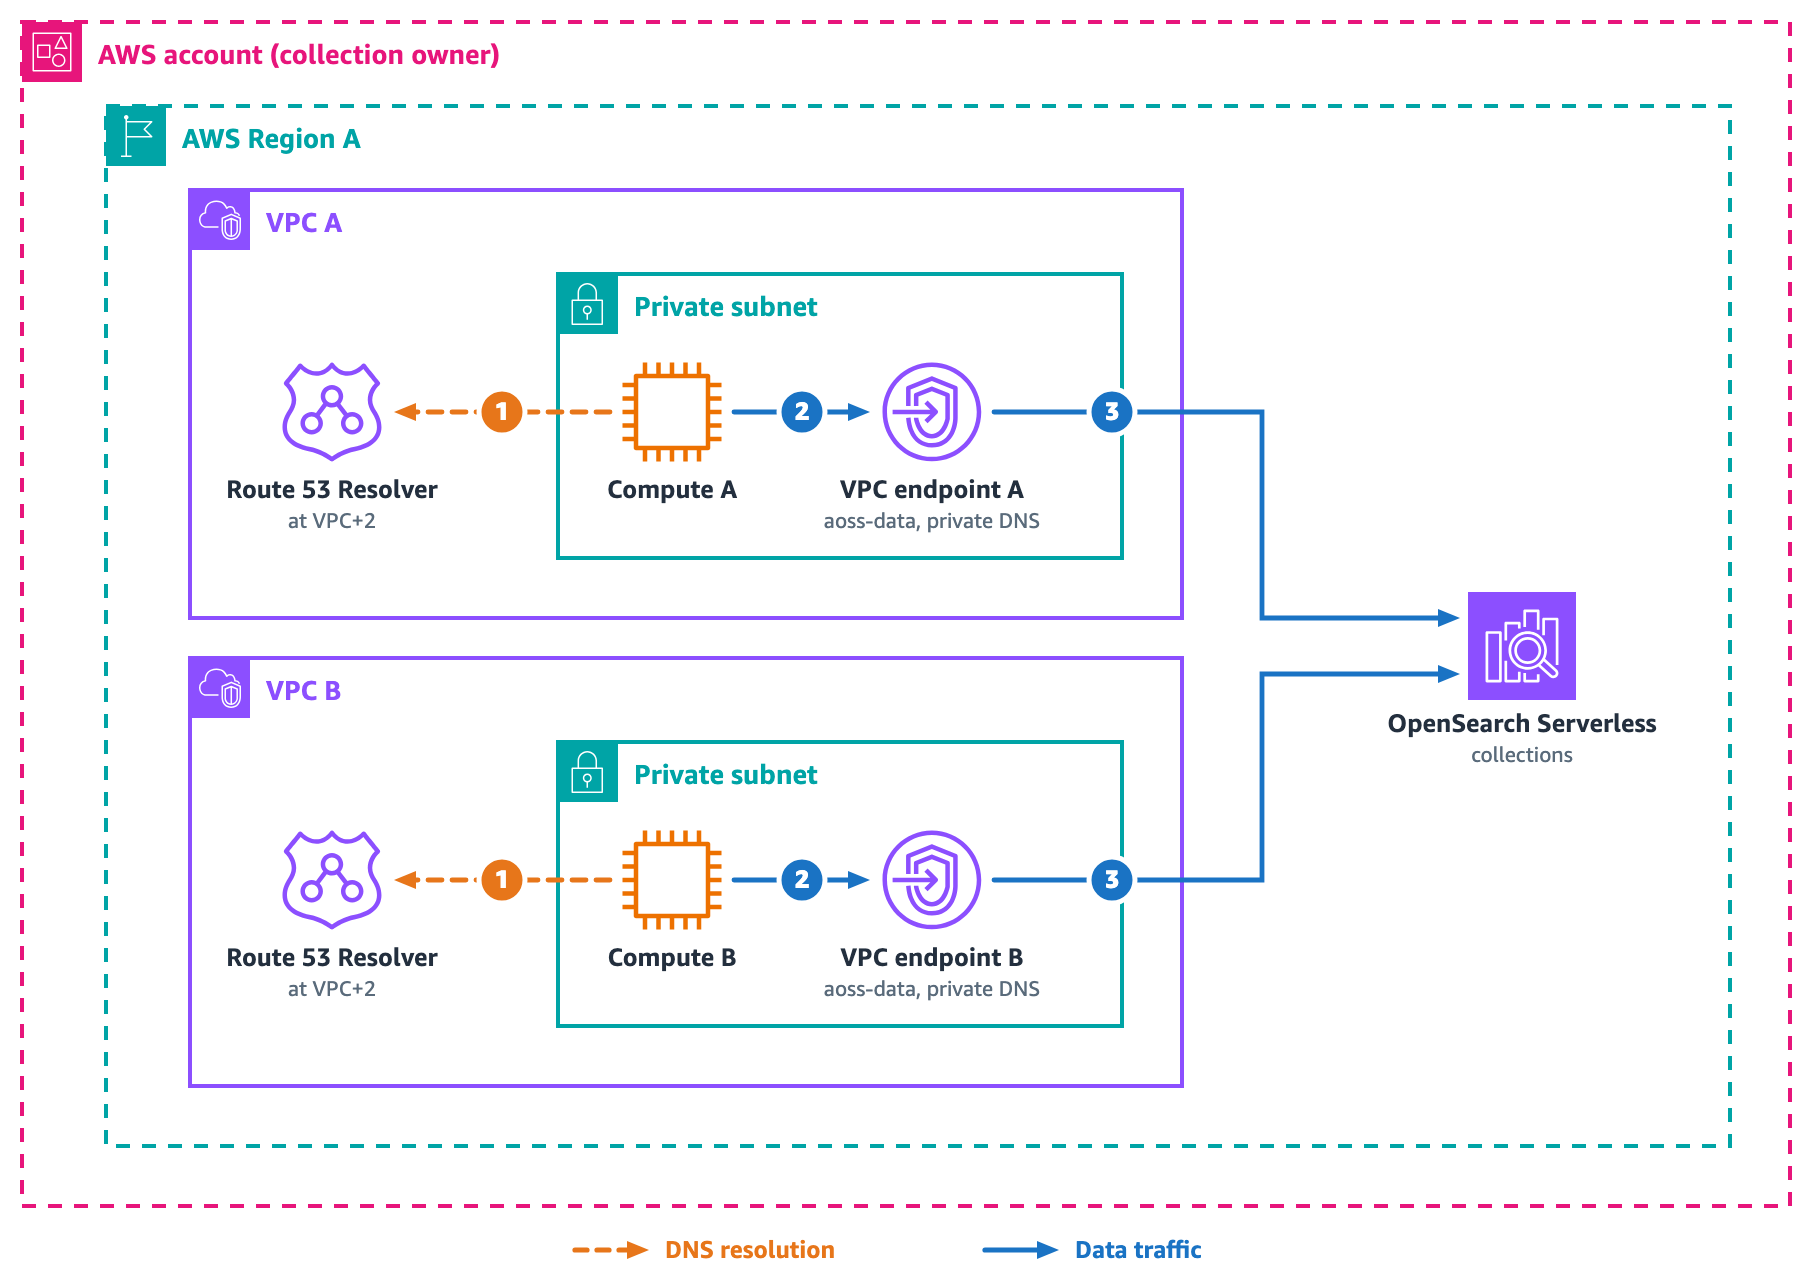
Figure 2: Multiple VPCs in the same account
Each VPC needs exactly one aoss-data endpoint with private DNS enabled, and that single endpoint already reaches every collection in the Region. DNS resolves independently within each VPC, so there is no cross-VPC DNS dependency. Adding a new VPC takes two steps. Create the endpoint, then add its endpoint ID to the collection’s network policy. Do not create a second aoss-data endpoint with private DNS enabled in the same VPC. Both endpoints share the same private hosted zone, which causes a conflict and the creation fails.
For the DNS resolution flow, (1) compute in each VPC queries the collection hostname, and that VPC’s Route 53 Resolver at VPC+2 returns the endpoint ENI IP addresses because private DNS is enabled on the endpoint.
For the data traffic path, (2) compute connects to its local ENI, and (3) PrivateLink forwards the request to the service, which routes to the collection by hostname.
On-premises clients reach collections over AWS Direct Connect or AWS Site-to-Site VPN, which connect to the VPC through AWS Transit Gateway or AWS Cloud WAN. The following diagram shows the DNS and data path for on-premises access.
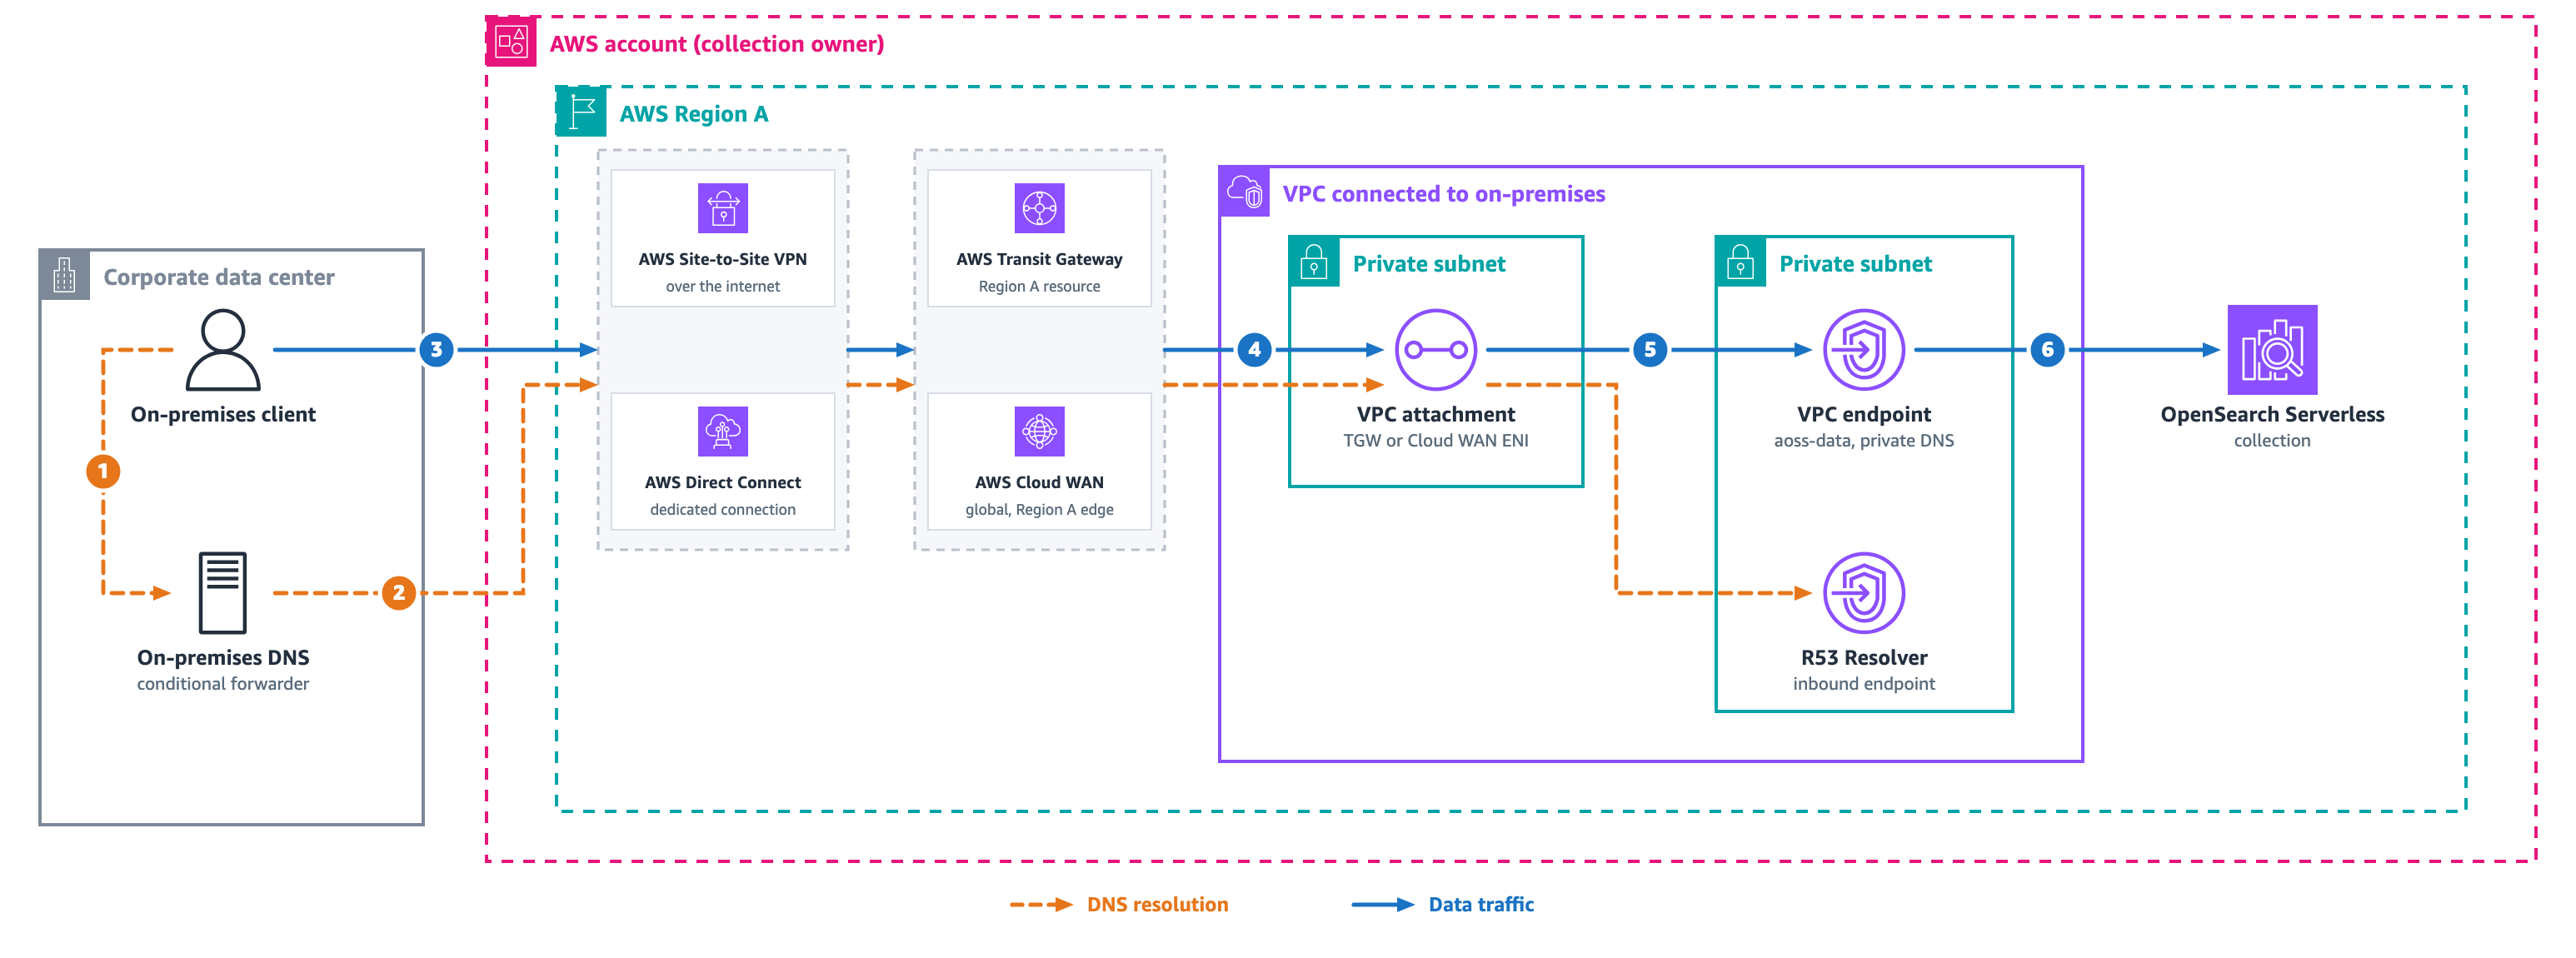
Figure 3: On-premises access from a single account
On-premises DNS servers sit outside the VPC and cannot resolve PrivateLink private DNS names directly. Place an Amazon Route 53 Resolver inbound endpoint in the VPC that holds the aoss-data VPC endpoint. On-premises DNS forwards queries for aoss.<region>.on.aws to that inbound endpoint. The inbound endpoint resolves them against the private hosted zone. The inbound endpoint’s security group must allow TCP/UDP port 53 from your on-premises resolver ranges.
For the DNS resolution flow, (1) the client queries the on-premises resolver. (2) The on-premises conditional forwarder for *.aoss.<region>.on.aws sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the endpoint’s private ENI IPs.
For the data traffic path, (3) the client sends an HTTPS request with the Transport Layer Security (TLS) Server Name Indication (SNI) header set to the collection hostname, over Direct Connect or VPN through Transit Gateway or Cloud WAN. (4) Traffic crosses the VPC’s attachment ENI, (5) reaches the VPC endpoint ENIs, and (6) PrivateLink forwards the request to the service.
A central account hosts collections, and compute in spoke accounts needs private access. Many enterprises start here. The following diagram shows the cross-account endpoint architecture.
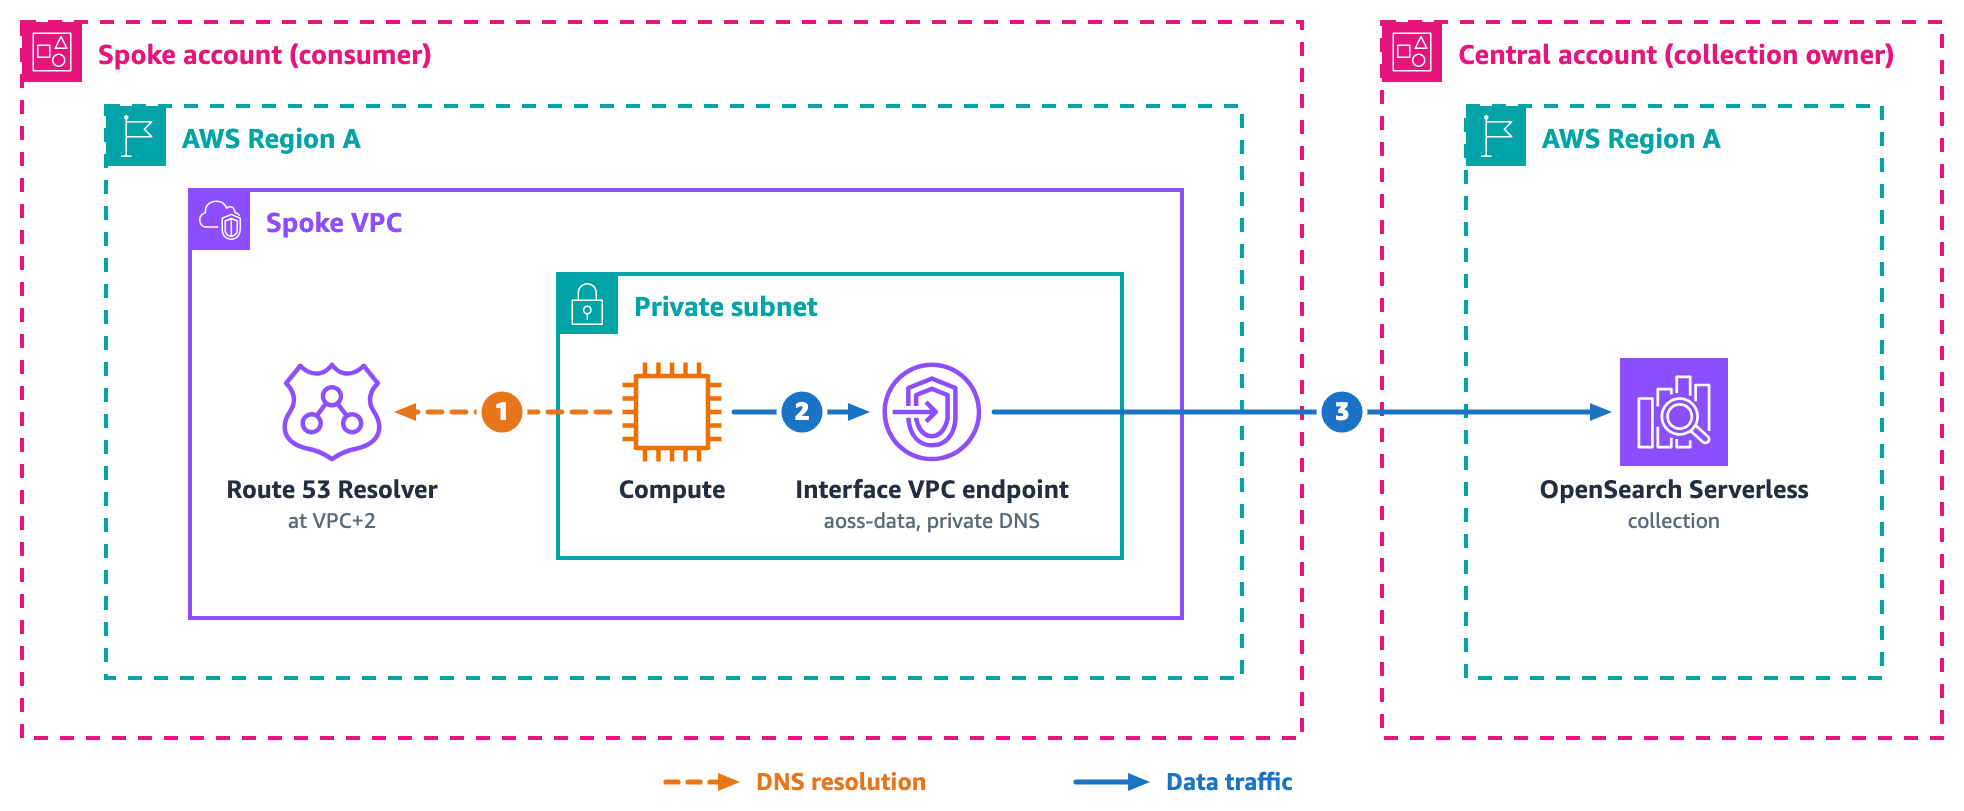
Figure 4: Cross-account access with an endpoint in each consumer VPC
Each spoke creates its own endpoint. The collection owner’s network policy references the spoke’s endpoint ID. The data access policy grants the spoke’s IAM role. PrivateLink carries the traffic end to end, with no Transit Gateway and no peering.
The endpoint lives in the spoke account, not the collection account. The spoke team creates a standard interface VPC endpoint in the spoke VPC for the service name com.amazonaws.<region>.aoss-data with private DNS enabled. The collection owner does not create this endpoint. After the endpoint is ready the spoke shares its endpoint ID with the collection owner, who adds that ID to the collection network policy under SourceVPCEs. A network policy accepts endpoint IDs from accounts across your organization. Each spoke creates its own endpoint and shares the ID rather than peering VPCs or routing through another account’s endpoint.
Network access and data access stay separate. The network policy authorizes the endpoint, and the data access policy authorizes the identity. A serverless data access policy grants principals from the collection’s own account. For a spoke in another account, you create an IAM role in the collection account and grant that role in the data access policy. The spoke role then assumes it to sign requests.
The following network access policy lists the two spoke endpoint IDs under SourceVPCEs and sets AllowFromPublic to false, so only those endpoints reach the collection and the policy denies public access.
For the DNS resolution flow, (1) spoke compute queries the VPC Route 53 Resolver at VPC+2, which returns the local endpoint ENI IPs because private DNS is enabled on the endpoint.
For the data traffic path, (2) compute connects to the local ENI. (3) PrivateLink forwards the request to the service, which checks the network policy for the endpoint ID and the data access policy for the IAM role before routing. Adding a spoke takes one API call and two policy edits.
You want fewer PrivateLink endpoints, so you run one shared endpoint in a networking VPC and reach it from spoke accounts over Transit Gateway or AWS Cloud WAN, with no endpoint in each spoke. The following diagram shows this centralized architecture.
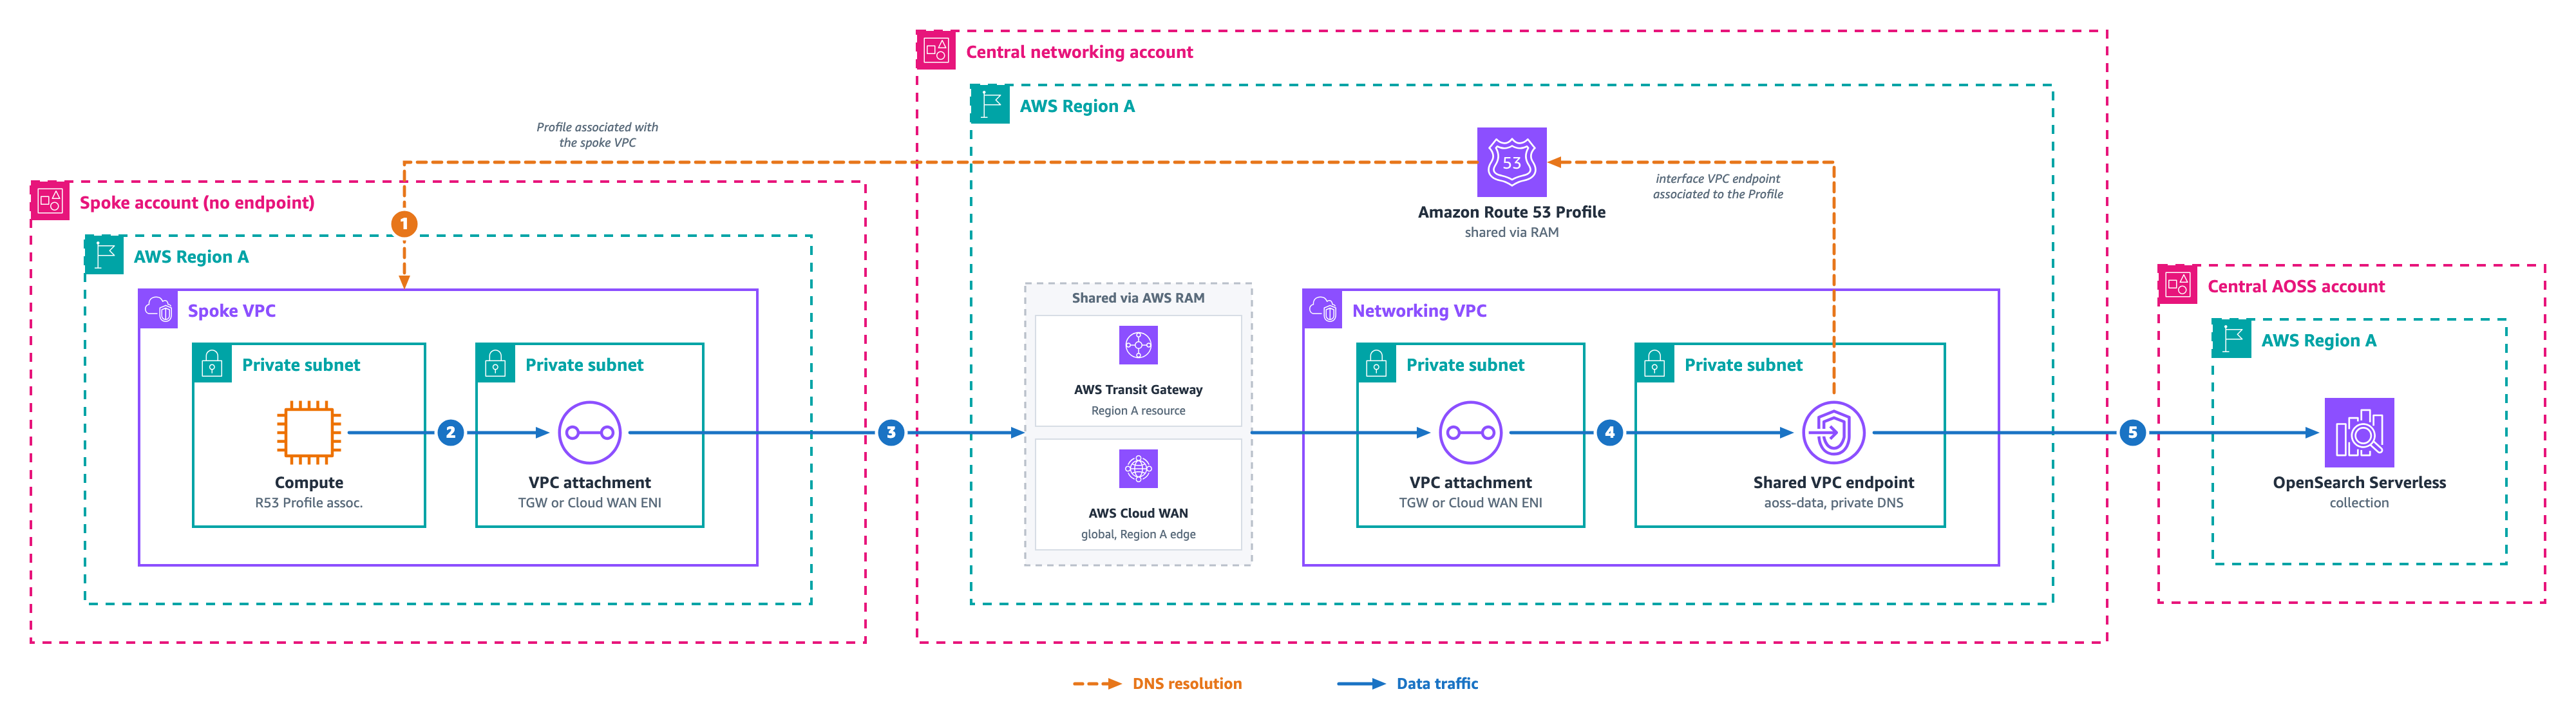
Figure 5: Centralized shared endpoint with Amazon Route 53 Profiles over Transit Gateway
Pattern 5 consolidates access through a single shared endpoint in a central networking VPC rather than creating one per spoke. Because spoke VPCs have no local endpoint, they cannot resolve *.aoss.<region>.on.aws on their own. You share the endpoint’s private DNS with spoke VPCs using Amazon Route 53 Profiles, shared through AWS Resource Access Manager (AWS RAM). This is the one pattern where you still manage DNS propagation.
For the DNS resolution flow, (1) the spoke resolves the hostname through the shared Route 53 Profile, which returns the networking-VPC endpoint ENI IPs.
For the data traffic path, (2) traffic leaves the compute through the spoke VPC’s attachment ENI, (3) crosses Transit Gateway or Cloud WAN into the networking VPC’s attachment ENI, (4) reaches the shared endpoint ENIs, and (5) PrivateLink forwards the request to the service.
A central account hosts collections. A separate networking account owns Direct Connect or VPN and Route 53. On-premises clients reach the collections through the networking account. The following diagram shows this architecture.
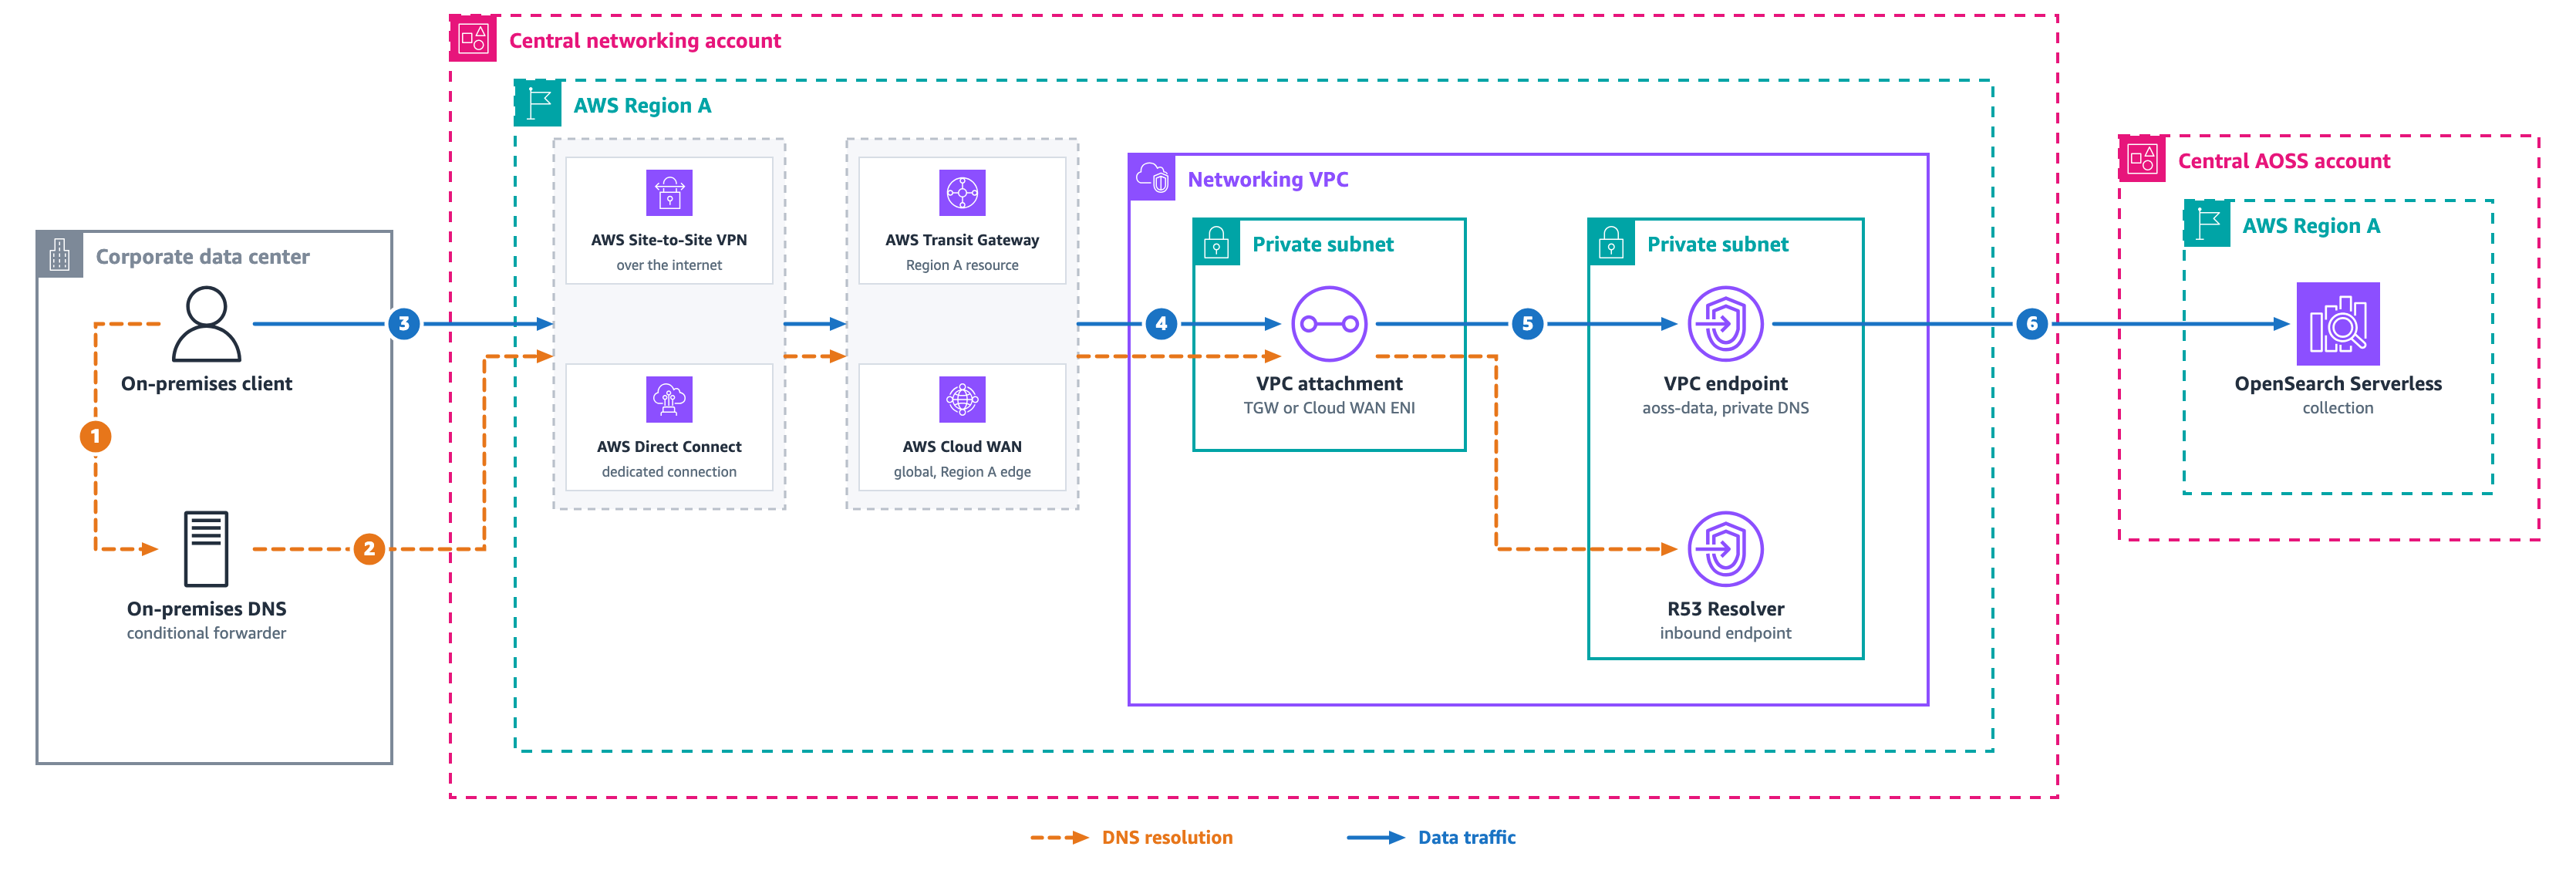
Figure 6: Cross-account centralized networking with on-premises
The networking account runs the standard VPC endpoint and a Route 53 Resolver inbound endpoint. The collection owner’s network policy references the networking account’s endpoint ID.
For the DNS resolution flow, (1) the on-premises client queries its resolver. (2) The on-premises conditional forwarder sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the endpoint’s private ENI IPs.
For the data traffic path, (3) the client sends HTTPS over Direct Connect or VPN, through Transit Gateway or Cloud WAN. (4) Traffic crosses the networking VPC’s attachment ENI, (5) reaches the networking-VPC endpoint ENIs, and (6) PrivateLink forwards the request to the service in the central account. The two teams coordinate through one artifact, the endpoint ID.
Spoke accounts such as analytics or application teams need collections spread across several business unit accounts, and each unit manages its own collections. The following diagram shows the distributed multi-business-unit architecture.
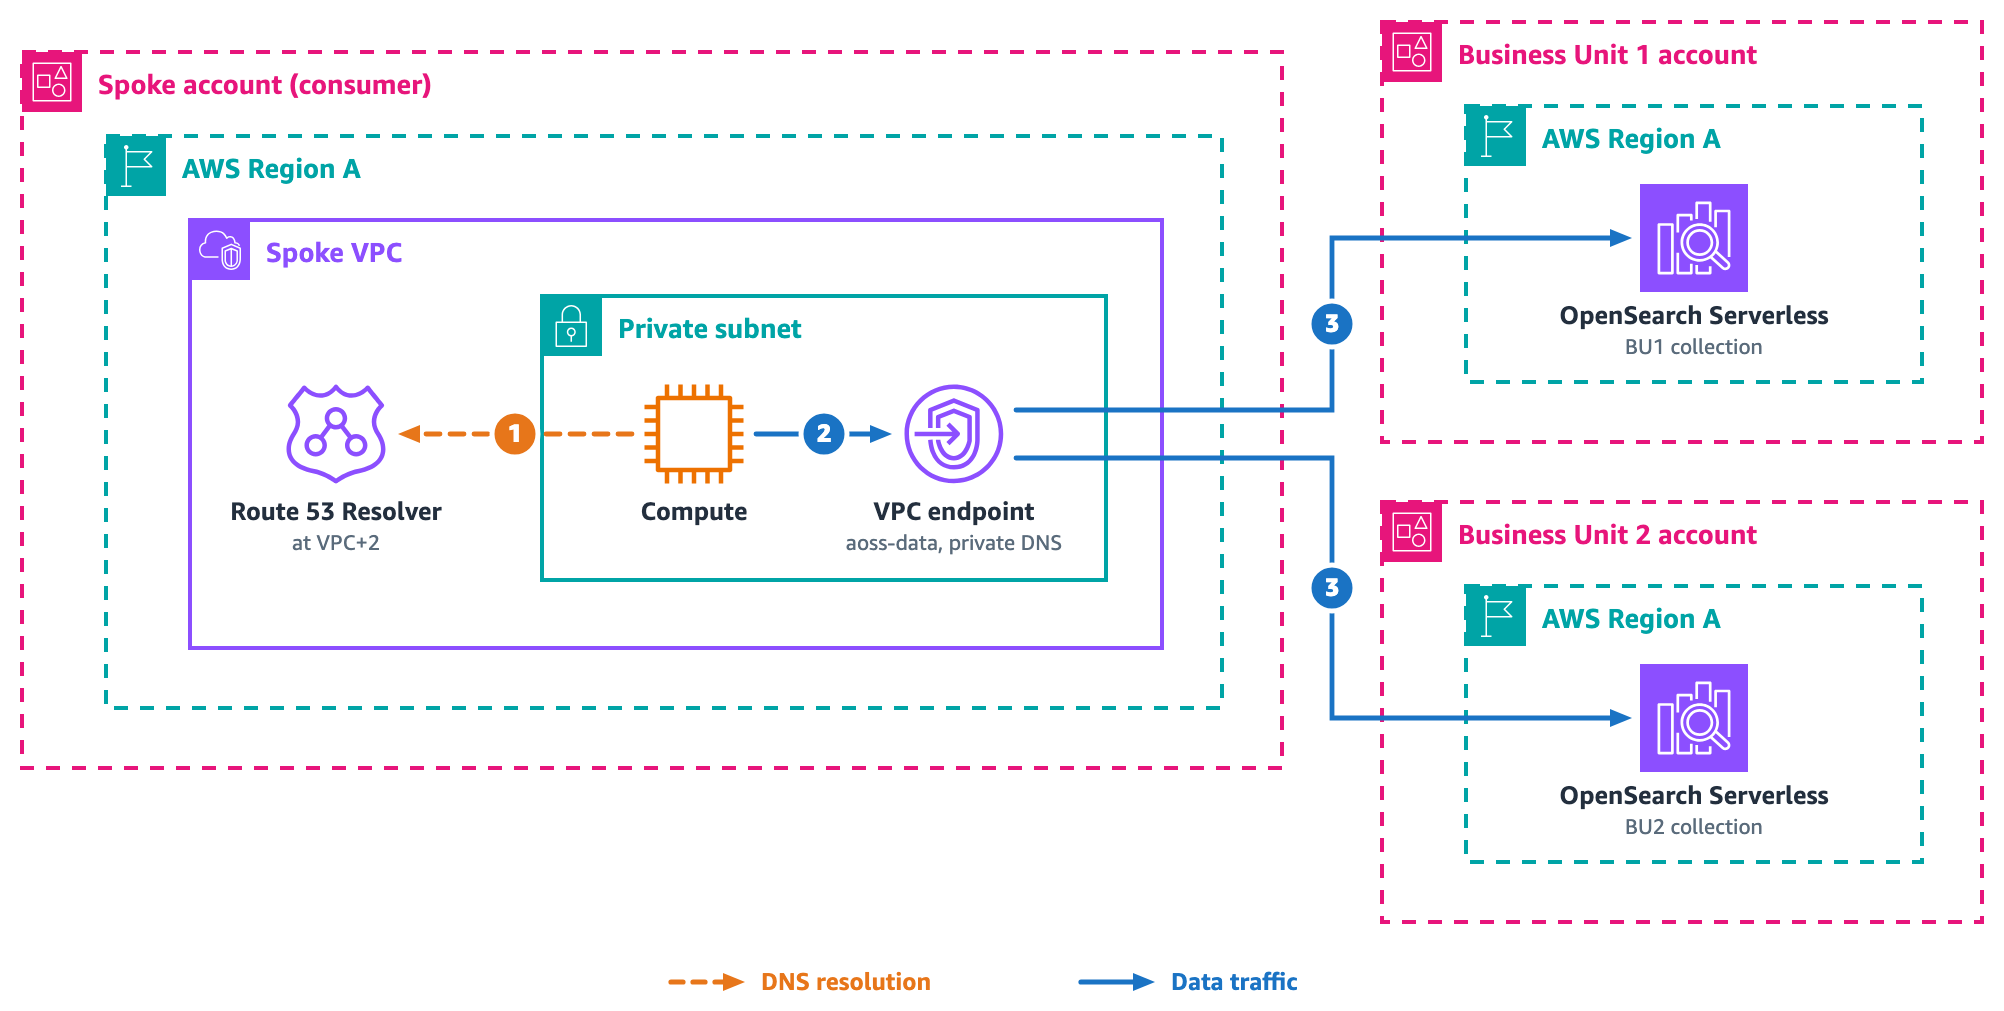
Figure 7: Distributed multi-business-unit with spoke-account access
Each spoke creates one standard endpoint, which resolves every collection hostname in the Region. Each business unit’s network policy lists the spoke endpoint IDs. Access control decides which collections a spoke reaches. DNS does not.
For the DNS resolution flow, (1) spoke compute queries the VPC Route 53 Resolver at VPC+2, which returns the endpoint ENI IPs because private DNS is enabled on the endpoint.
For the data traffic path, (2) compute connects to the local ENI, and (3) PrivateLink forwards the request to the service, which routes to the correct business unit collection by hostname.
| Action | Required change |
| New collection in any BU | No networking change is needed because in the network policy collection/* wildcard, already covers any new collection |
| New spoke account | Spoke creates an endpoint, and BUs add its ID to their policies |
| Remove spoke access | BUs remove the endpoint ID and the IAM principal |
Several business units own collections in separate accounts. On-premises clients reach collections across all of those accounts through a central networking account. The following diagram shows this architecture.
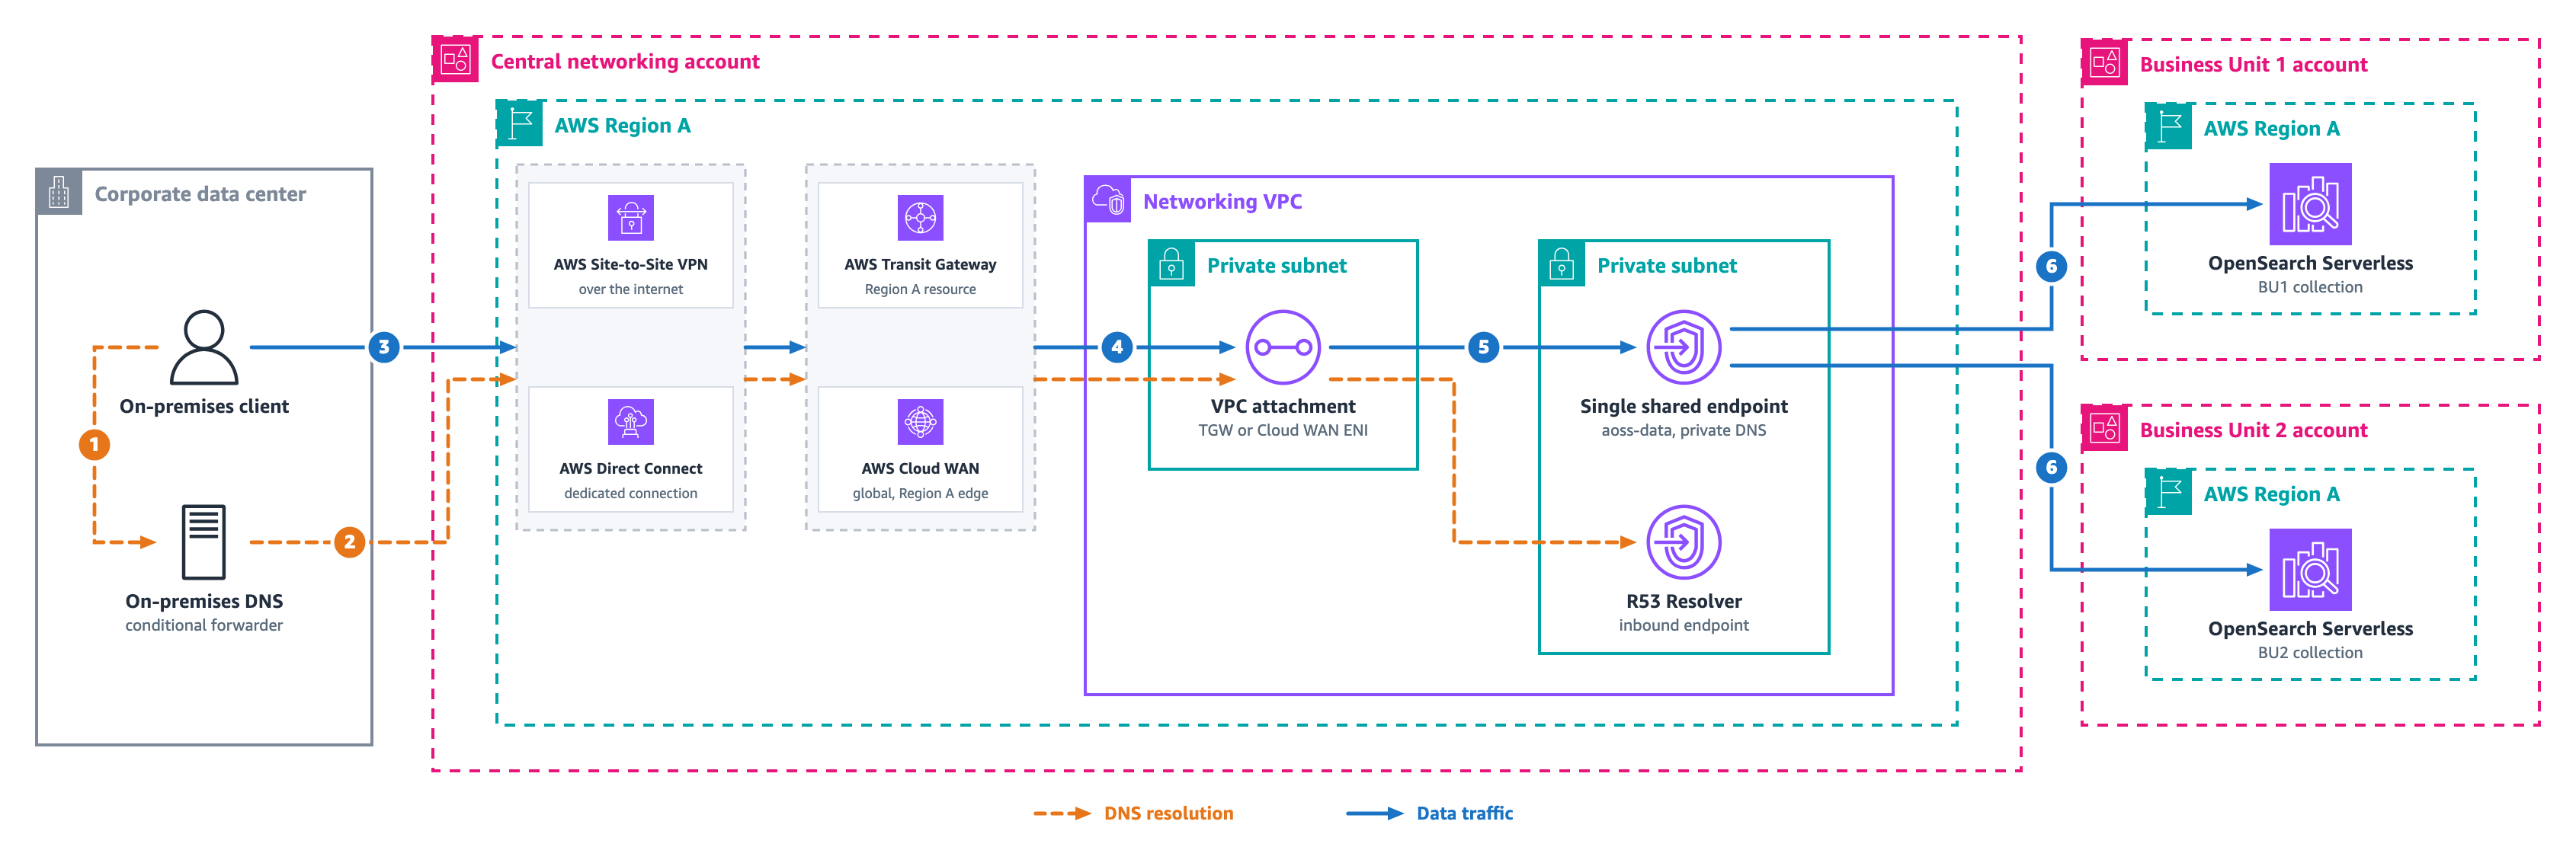
Figure 8: Distributed multi-business-unit with on-premises access
The networking account runs one standard endpoint that resolves *.aoss.<region>.on.aws hostnames, regardless of which account owns the collection. Each business unit’s network policy includes the networking endpoint ID.
For the DNS resolution flow, (1) the on-premises client queries its resolver. (2) The on-premises conditional forwarder for *.aoss.<region>.on.aws sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the networking VPC’s inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the shared endpoint’s private ENI IPs.
For the data traffic path, (3) the client sends HTTPS over Direct Connect or VPN, through Transit Gateway or Cloud WAN. (4) Traffic crosses the networking VPC’s attachment ENI, (5) the request arrives at the shared endpoint ENIs, and (6) the service routes to business unit 1 or business unit 2 by hostname, as long as that business unit’s policy lists the networking endpoint ID. Adding a collection in any business unit needs no networking change if the network policy uses a collection/* wildcard, since the wildcard already covers it.
Consumers in Region B need data that lives in collections in Region A. The following diagram shows cross-Region access strategies.
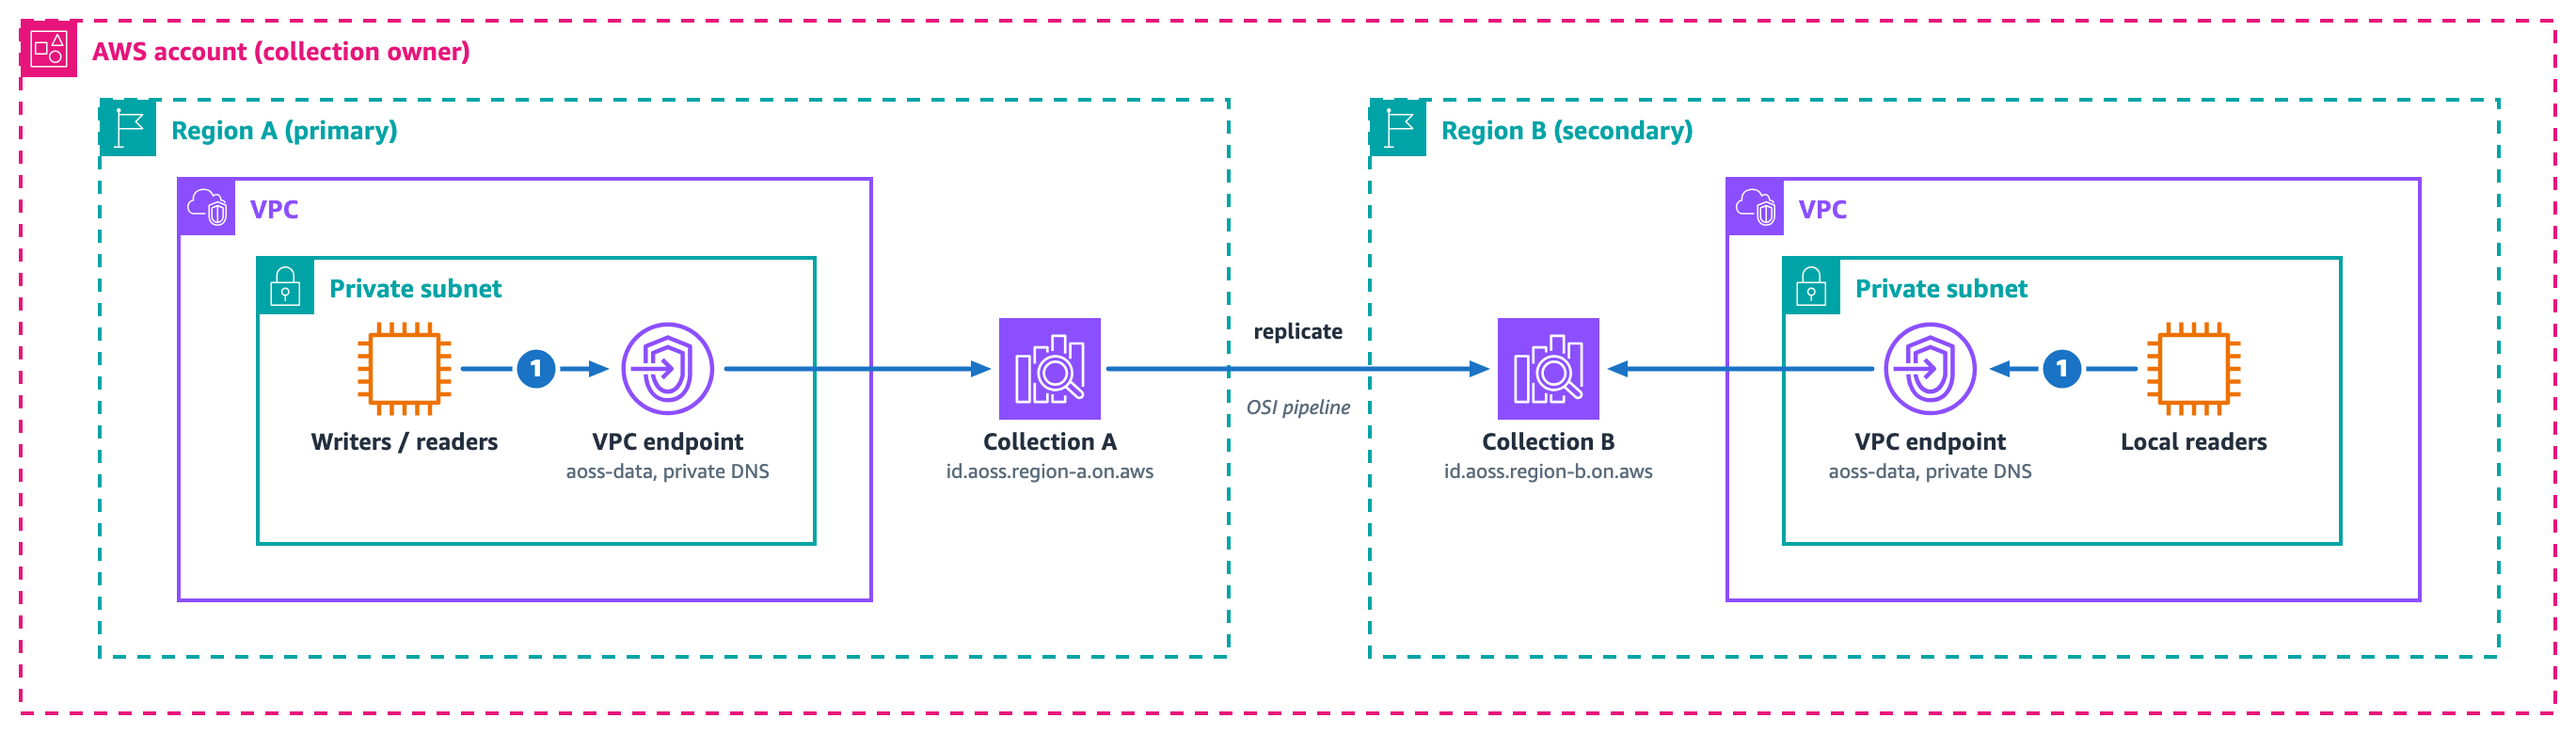
Figure 9: Cross-Region access strategies
Collections are Regional. No built-in cross-Region endpoint or replication exists. Deploy independent collections in each Region, each with its own endpoint and policies, then synchronize data with one of these approaches.
For the DNS resolution flow, DNS resolves locally in each Region, the same as Pattern 1. Each collection hostname carries its Region, so a hostname in Region A resolves through Region A’s own endpoint and a hostname in Region B resolves through Region B’s own endpoint, with no cross-Region DNS.
For the data traffic path, (1) compute in each Region uses that Region’s own endpoint to reach its local collection. Writes land in the primary Region and the sync approach you choose replicates them to the secondary Region, where local readers query the replica. The replicate arrow shows that cross-Region movement, such as an OpenSearch Ingestion pipeline that writes into the secondary-Region collection.
Scale-to-zero changes the economics. An idle secondary-Region collection costs only storage until requests arrive.
| Pattern | Components |
| 1. Same VPC | Standard endpoint and network policy |
| 2. Multiple VPCs | Endpoint per VPC and a policy listing all IDs |
| 3. On-premises | Endpoint, Route 53 inbound endpoint, on-premises forwarder, and Transit Gateway or Cloud WAN |
| 4. Cross-account | Endpoint per consumer, network policy, and data policy |
| 5. Centralized shared endpoint | Shared endpoint, Route 53 Profiles through RAM, and Transit Gateway or Cloud WAN |
| 6. Central networking with on-premises | Networking endpoint, Route 53 inbound, forwarder, Transit Gateway or Cloud WAN, and policies |
| 7. Multi-BU with spoke access | Endpoint per spoke, and each BU policy lists spoke IDs |
| 8. Multi-BU with on-premises | One networking endpoint reached through Transit Gateway or Cloud WAN, and each BU policy lists its ID |
| 9. Cross-Region | Independent collections per Region and a data-sync approach |
Across each private pattern, the VPC endpoint resolves all *.aoss.<region>.on.aws hostnames through standard PrivateLink private DNS. Network policies control which endpoints reach a collection, and data access policies control which principals operate on the data. Only Pattern 5 asks you to manage DNS.
The connectivity pattern you choose drives recurring cost, so match it to your scale instead of adding infrastructure you do not need. The two charges that come up most often, a Route 53 Resolver inbound endpoint and Route 53 Profiles, are both optional for access that stays inside AWS.
A Route 53 Resolver inbound endpoint is needed only for the on-premises patterns (3, 6, and 8), where an on-premises resolver forwards queries into the VPC. Traffic that stays inside AWS never uses it. Route 53 Profiles apply only when a VPC has no endpoint of its own, as in Pattern 5, where the profile carries the shared endpoint’s private DNS to the spoke. When each VPC runs its own interface endpoint, DNS resolves locally through the VPC Route 53 Resolver at no extra charge, so neither the inbound endpoint nor a profile is required.
For most multi-account and multi-Region deployments, an interface endpoint in each consumer VPC (Pattern 4) is the least complex and often the least expensive option. You pay for the interface endpoints you already need for private access, and local DNS resolution adds nothing. Because collections are Regional and each Region resolves on its own, this scales across Regions with no cross-Region DNS.
Centralizing on one shared endpoint (Pattern 5) lowers the number of interface endpoints. However, it adds Transit Gateway or Cloud WAN data processing charges and the cost of sharing DNS. You share that DNS either through Route 53 Profiles or through a private hosted zone that you associate across accounts and maintain yourself. A smaller endpoint count is not automatically cheaper because transit data processing can exceed the savings. Compare both designs against your own traffic before you decide.
Scale to zero also shapes cost. An idle collection, such as a secondary-Region replica in Pattern 9, releases its compute and bills only for storage until requests arrive. For current rates, see AWS PrivateLink pricing, Amazon Route 53 pricing, and Amazon OpenSearch Service pricing.
OpenSearch Serverless uses standard AWS PrivateLink for private connectivity. You create a VPC endpoint, enable private DNS, and reference the endpoint ID in your network policy. The model scales from single-VPC access to multi-account and multi-business-unit designs, and only Pattern 5 adds DNS infrastructure, where you share the endpoint’s private DNS with Route 53 Profiles. The per-account regional endpoint goes further and serves any collection in an account through one hostname and connection pool. To get started, create your first collection in the OpenSearch Serverless console, or explore the OpenSearch Serverless documentation for detailed API references and tutorials.
Post Syndicated from Saar Porat original https://aws.amazon.com/blogs/big-data/how-moovit-achieved-33-cost-optimization-through-architectural-modernization/
Moovit, part of Mobileye (Nasdaq: MBLY), is a leading Mobility-as-a-Service (MaaS) solutions provider and the creator of a leading urban mobility app. Moovit’s iOS, Android, and web apps offer users a smart mobility experience to get to their destination using any mode of public and shared transportation. Transit riders can benefit from mobile ticketing to plan, pay, and ride with transit services. Introduced in 2012, Moovit now serves over 1.7 billion users in more than 3,500 cities across 112 countries, in 45 languages.
Behind these user-facing experiences is a data platform that processes large volumes of mobility, application, and operational data to support product analytics, business intelligence (BI), monitoring, and data science. As the platform grew, Moovit needed to keep analytical workloads reliable and cost-efficient without slowing down teams that depend on fresh data every day.
Over several years, Moovit’s Amazon Redshift cluster grew continuously. It started with an expanding fleet of DC2 nodes, migrated to RA3 nodes, and scaled multiple times to keep pace with growing data demands, ultimately becoming the backbone of their entire data platform.
To address this growth, Moovit transformed their data architecture by building an optimal multi-engine lakehouse architecture and assigning each workload to the most suitable option. This modernization reduced their Amazon Redshift cluster by 50 percent, while establishing a flexible, multi-engine architecture ready for future use cases.
In this post, we share how Moovit gained visibility into workload patterns, cleaned up unnecessary load, selected candidates for offloading, and ran a successful proof of concept (POC) on Amazon EMR Serverless. Moovit ultimately divided the workload between multiple engines, building a modern and cost-optimized data platform that combines provisioned Amazon Redshift, Amazon Redshift Serverless, and Amazon EMR.
The Amazon Redshift engine handled a wide variety of workloads, including:
With business growth, storage grew by orders of magnitude over the past decade as the platform expanded. All these varied workloads competed for the same engine and pushed it to its limits. Jobs experienced increasing queue times, service level agreements (SLAs) were at risk, and adding nodes provided minimal performance gains, creating a need to isolate workloads.
Moovit’s first modernization milestone was to create a trusted measurement foundation before changing any workloads. Instead of treating warehouse activity as a single opaque stream, the team implemented automated query attribution that continuously classified each query by workload owner and execution context. The classification combined multiple signals: who executed the query (user or service account), recognizable query-signature patterns, and metadata emitted by orchestration frameworks and scheduled processes.
This produced a historical, query-level map of platform usage that answered three critical questions: who is generating load, what kind of workload is running, and how expensive each workload is in runtime and resource terms. With that baseline in place, the team made offload decisions from evidence rather than assumptions. This approach prioritized the largest and most stable optimization opportunities first and reduced the risk of moving business-critical workloads without visibility.
These classifications and workload metrics were reflected in a Tableau report that aggregated query activity by classification label and execution context. The view exposed operational dimensions such as classification, time granularity, service class, execution-time bucket, unload flags, and sample-query context, supporting both trend monitoring and root-cause drill-down.
The worksheet was parameterized to support multiple measurement modes over the same grouped workload population: total execution time, execution plus queue time, total CPU time, average execution time per query, and ratio-based efficiency views (execution/CPU and CPU/execution). This let the team compare “heavy by volume” workloads against “inefficient by behavior” workloads without creating separate artifacts.
For decision-making, CPU time was used as the primary impact metric because it best represented sustained compute pressure. Execution time, queue time, query-count normalization, and workload-management segmentation were treated as secondary evidence to distinguish:
Using this framework, prioritization became systematic: first improve classification coverage, then rank workloads by CPU contribution, then validate with queue and workload management (WLM) signals, and finally choose the action path per workload (optimize SQL, reschedule, isolate, retire, or move to another engine).
The following figure shows an example of one of the dashboard widgets (CPU time by query).
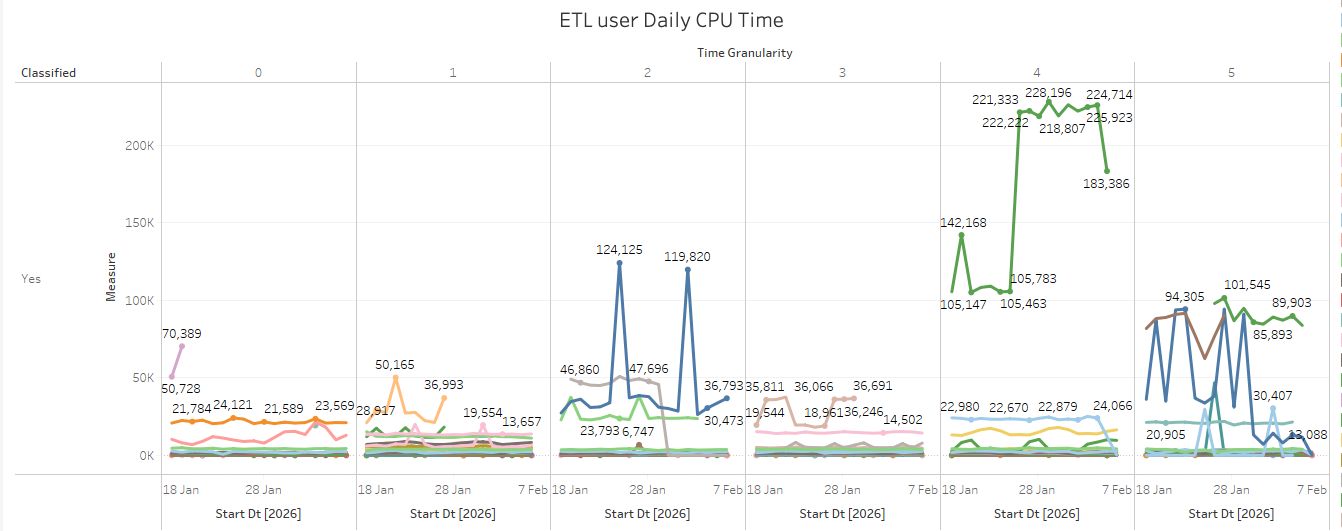
Figure 1: CPU time by query, highlighting the most resource-intensive queries and their usage patterns
With a long-running data platform, in most cases the workloads will start accumulating, some of which become irrelevant at some point. For example, a report which was created and scheduled, yet it became irrelevant after a few years, but still running since no one disabled it. It’s important to indicate these workloads in general to reduce unnecessary load, yet even more critical before doing any significant architectural changes or migrations. Before migrating any workloads, Moovit first reduced unnecessary warehouse load.
The team:
This cleanup phase was a prerequisite to migration. By removing waste first, the team verified that the workloads eventually selected for offloading were genuinely heavy rather than simply unoptimized or unnecessary.
The no-longer-relevant processes consumed around 7 percent of overall CPU time and were removed before the optimization work began.
With a clear picture of workload patterns, Moovit faced a common decision point: continue scaling the existing Redshift cluster, or re-architect towards a multi-engine approach. The team evaluated two main paths:
Moovit decided to do both, because while some workloads benefited from being offloaded, others benefited from isolated Amazon Redshift compute.
The measurement data revealed a primary candidate for offloading: raw-data aggregation pipelines. This workload loaded raw data into Amazon Redshift from Amazon S3, then performed heavy sessionization and aggregation transformations. Raw tables were still used for ad-hoc and exploratory analysis, but recurring production consumers primarily depended on aggregated outputs, making these transformations strong candidates for offloading.
With target workload identified, Moovit initiated a POC using Amazon EMR Serverless with Spark SQL. The choice of EMR Serverless was driven by several factors:
The POC defined quantified success criteria measured over five or more consecutive runs:
The first POC attempts exposed significant challenges. Early Spark jobs with 100 executors took approximately 4 hours, far exceeding the 30–40-minute baseline on Amazon Redshift. Beyond raw performance, the team encountered memory pressure, data-parity gaps between Spark and Amazon Redshift outputs, and subtle SQL behavior differences between the two engines.
The team systematically diagnosed and resolved these issues:
After applying these optimizations, execution time dropped from 4 hours to approximately 10 minutes, and the required executors dropped to fewer than 50, surpassing the original performance.
Before transitioning any workload to production, Moovit implemented a rigorous validation process. The new Spark output was compared with the previous Amazon Redshift output using multiple dimensions:
Only after all validation checks passed consistently over multiple consecutive runs did the team proceed with cutover for each workload.
With a successful POC demonstrating both performance gains and cost savings, Moovit progressively moved additional workloads from Amazon Redshift to EMR:
The transition used a measured approach: each workload was migrated individually, with data-quality validation confirming parity before decommissioning the equivalent jobs which were running on Redshift.
Beyond EMR offloading, Moovit implemented further architectural improvements to isolate workloads and optimize costs.
With heavy workloads successfully offloaded and isolated, Moovit proceeded to right-size the Redshift cluster. Rather than a single resize, the team reduced the cluster incrementally, two nodes at a time, using elastic resize. At each step, they validated that:
This iterative approach minimized risk and allowed the team to find the optimal cluster size with confidence.
Amazon Redshift persisted as the engine of choice for serving curated BI data. However, not all Amazon Redshift workloads needed provisioned capacity:
This workload isolation through Redshift Serverless provided resource separation without requiring additional provisioned capacity. The architecture now used data sharing to provide a unified view across provisioned and serverless clusters.
Moovit also refined workload isolation by rebalancing WLM priorities on the provisioned cluster. Because the ETL queue mainly handled raw data loading from Amazon S3 (which was not the bottleneck after heavy aggregations moved to Spark), its priority was reduced. At the same time, with most human users moved to Redshift Serverless, Tableau serving workloads on provisioned Redshift were prioritized higher to keep dashboard performance predictable. The final result: a 50% reduction in provisioned Redshift capacity.
EMR Serverless proved efficient for the POC phase: it allowed fast iteration without cluster management overhead. However, for longer-term recurring production workloads, Moovit moved to EMR on EC2 to better fit their production cost and infrastructure model, using existing compute reservations.
The transition between EMR deployment options required zero application code changes, demonstrating the flexibility of the EMR deployment options.
Additionally, Moovit used AI-assisted development tools, Claude Code and Cursor, to accelerate parts of the SQL transition process. These tools helped engineers identify Redshift SQL and Spark SQL syntax differences, suggest rewrites, and debug migration issues, while validation and production approval remained under engineer review.
The architectural modernization delivered measurable outcomes:
The following figures compare aggregation-job performance before and after the transition.
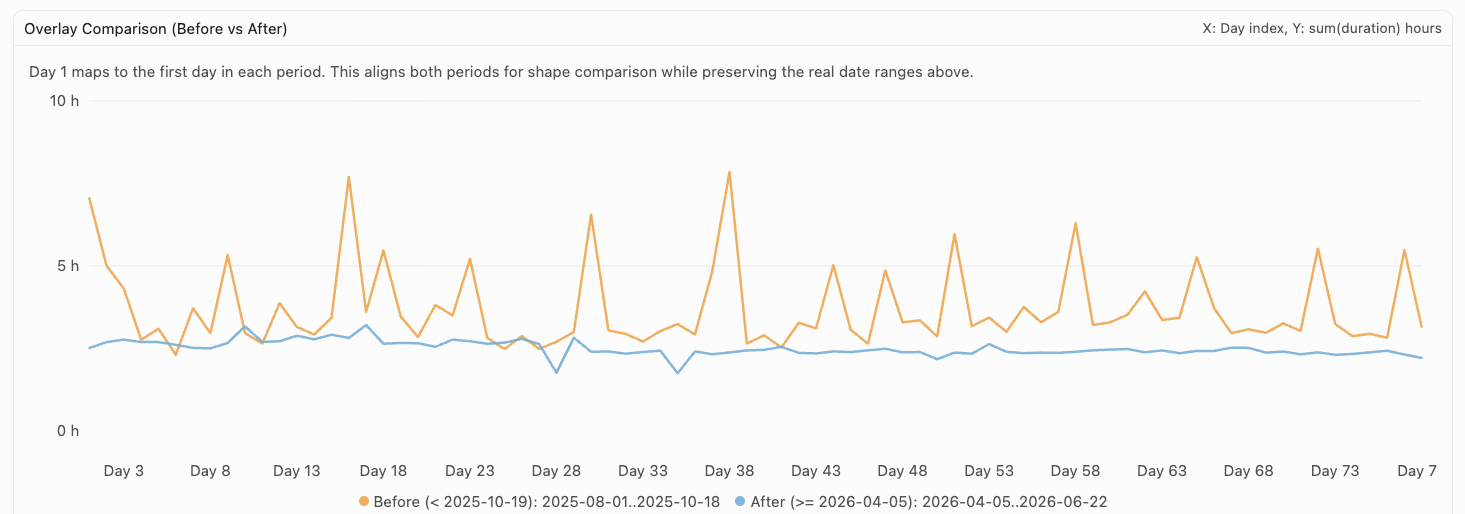
Figure 2: Aggregation-job execution times before and after the transition
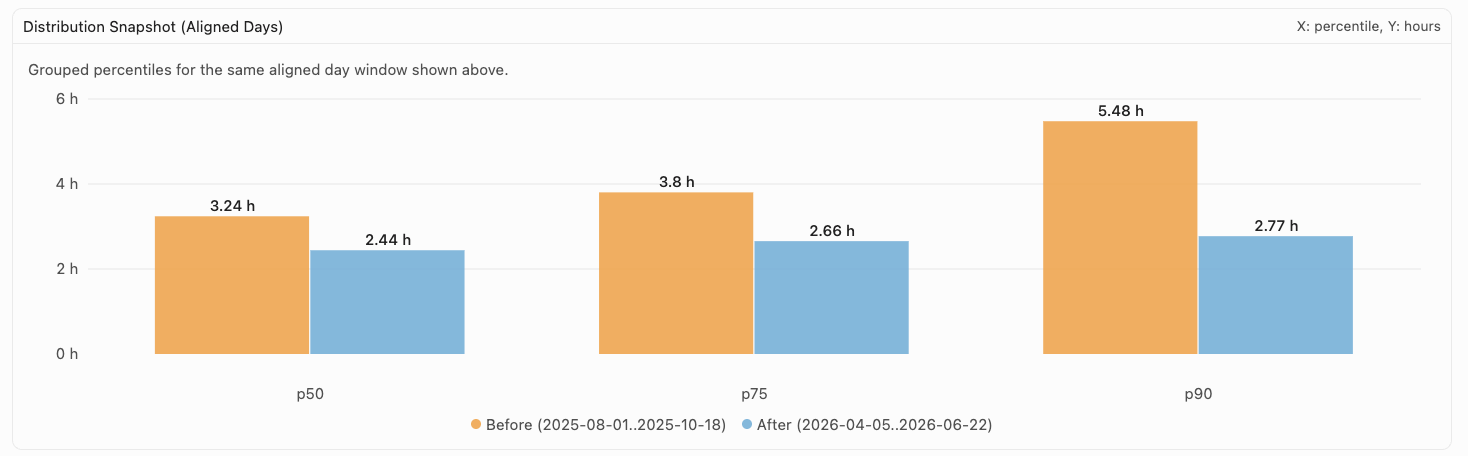
Figure 3: Wall-clock time for job executions by percentile, before and after the transition
The resulting architecture assigned each workload to the engine that fits it best:
| Workload type | Engine | Rationale |
| Heavy ETL and aggregation | Amazon EMR (Spark SQL) | Distributed processing on Amazon S3. No data warehouse load required |
| Ongoing processing and BI reporting | Amazon Redshift provisioned | 24/7 running processes |
| Ad-hoc queries | Amazon Redshift Serverless | Burst capacity with workload isolation |
| Data science | Amazon Redshift Serverless | Flexible exploration without impacting production |
The Moovit modernization journey produced several key insights applicable to similar architectural transitions:
Looking ahead, as another potential optimization, Moovit will be evaluating the new Amazon Redshift RG instances for provisioned clusters, providing up to 2.2x better price performance and priced 30% lower than RA3, powered by AWS Graviton.
The broader takeaway is that AWS provides multiple purpose-built engines that can be used in a single data platform. In Moovit’s case, the biggest improvement came from assigning each workload to the engine that fit it best: Amazon Redshift for curated analytical serving, Redshift Serverless for isolated exploratory workloads, and Amazon EMR for large-scale transformations over data in Amazon S3. This architecture gives Moovit a foundation for future optimization and flexibility as data volumes grow and new analytical use cases emerge.
Post Syndicated from Rohit Kumar original https://www.servethehome.com/mikrotik-crs804-4ddq-hrm-review-marvell-annapurna-labs-400gbe/
We test the MikroTik CRS804-4DDQ-hRM a 4-port 400GbE network switch that we have been using for local AI clusters
The post Cheap Desktop 400GbE Switch MikroTik CRS804-4DDQ-hRM Review appeared first on ServeTheHome.
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=CoguNLZtdgI
Post Syndicated from corbet original https://lwn.net/Articles/1092001/
Tiered-memory systems are built with multiple types of memory, each of
which has different performance characteristics. In addition to the usual
DRAM, a tiered system might also provide faster high-bandwidth memory or
slower CXL memory. On these systems, the placement of memory allocations
has a significant effect on the performance that a workload will obtain.
While work on tiered-memory improvements has been ongoing for years, it
feels like the pace has slowed a bit recently. Even so, there are a few
efforts underway, but they are facing questions about whether the tiering
design makes sense.
Post Syndicated from jzb original https://lwn.net/Articles/1092439/
Version
4.0 of the Audacity audio editor has been released. Notable changes in this
release include a rewritten interface using Qt, ability to save user-interface
layouts as “Workspaces”, improvements in working with audio clips, and a new
.aup4 project format.
The release is not fully feature-compatible with the Audacity 3.x
series; see the compatibility
notes for a list of missing features.
Post Syndicated from jzb original https://lwn.net/Articles/1092419/
Security updates have been issued by AlmaLinux (freerdp, go-fdo-server, golang-github-openprinting-ipp-usb, kernel, kernel-rt, nodejs:24, perl-DBI, and php), Debian (firefox-esr, libapache2-mod-auth-openidc, and libass), Fedora (dracut, exiv2, firefox, freerdp, gvfs, mingw-expat, mingw-gstreamer1, mingw-gstreamer1-plugins-bad-free, mingw-gstreamer1-plugins-base, mingw-gstreamer1-plugins-good, mingw-openexr, nss, proftpd, and syncthing), Mageia (apr-util, bubblewrap, libalsa2, libarchive, perl-Net-OAuth, perl-Text-CSV_XS, perl-XML-Bare, and perl-YAML-Syck), Oracle (freerdp, gimp, golang, iperf3, nginx:1.24, nodejs:22, nodejs:24, pipewire, wget, xmlrpc-c, and xorg-x11-server-Xwayland), SUSE (apache2-mod_auth_openidc, apptainer, apr-util, bzip2, c-ares, cosign, dhcpcd, dovecot22, emacs, erlang, gegl, gopass, gzip, httpcomponents-client, incus, kernel-devel, libgpg-error, libsoup2, mozillafirefox, mozilla-nss, mozilla-nspr,, MozillaFirefox, mozilla-nss, mozilla-nspr, rust-cbindgen, nodejs20, orthanc, orthanc-authorization, orthanc-postgresql,, postgresql14, python-cryptography, python-msgpack, quagga, snpguest, snphost, texlive, tuxguitar, udisks2, vim, wget, and yast2-users), and Ubuntu (apr-util, biosig, linux, linux-aws, linux-azure, linux-azure-fips, linux-fips,
linux-hwe-5.4, linux-ibm, linux-ibm-5.4, linux-iot, linux-kvm,
linux-oracle, linux-raspi, linux-raspi-5.4, linux-xilinx-zynqmp, linux-aws-5.15, linux-gcp-5.15, linux-oracle-5.4, sssd, and tika).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/researching-employment-scams.html
Researchers built a fake company to study fake employee scams.
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=9vXvGnezjWg
Post Syndicated from Greg Eppel original https://aws.amazon.com/blogs/devops/automating-the-experimentation-lifecycle-with-kiro-aws-devops-agent-and-launchdarkly/
Continuous improvement depends on experimentation. Teams know that the fastest path to better outcomes is to test changes against real user behavior, measure results, and iterate. In practice, sustaining that cycle is slow and costly because the overhead compounds with each attempt.
Three barriers slow teams down:
1. Planning cost — Turning a proposed change into a testable experiment requires defining a feature flag strategy, coordinating implementation, and wiring everything together before any user sees new behavior.
2. Measurement disconnected from action — Once live, teams must configure metrics, define success criteria, monitor, and interpret results. When metrics regress, remediation traditionally depends on a human merging a fix or rolling back a deployment.
3. Stalled iteration — Without a record of which change caused which outcome, the next hypothesis is a guess, so iteration often does not happen and the goal stalls.
This post introduces a reference solution that closes the gap between defining a goal and reaching it. A team states an improvement goal (for example, increase add-to-cart rate by 10%), and agents plan the experiment, implement the change, deploy it behind a feature flag, measure its impact, and iterate on the result, all within defined safety boundaries. The solution connects Kiro for code generation, AWS DevOps Agent for orchestration and release readiness review, and LaunchDarkly for feature flag governance, experiments, and Guarded Releases for safe, metric-driven rollouts with automatic rollback. The architecture described here is a reference implementation you can build today. A more turnkey experience is planned for the future.
Step 1. Enable AWS DevOps Agent and Create an Agent Space. AWS DevOps Agent is available in the AWS regions listed here. Follow these steps to create your AWS DevOps Agent and create an Agent Space.
Step 2. Create your LaunchDarkly account. Create your LaunchDarkly account using the AWS Marketplace or through LaunchDarkly website.
Step 3. Enable the LaunchDarkly MCP Server in the Agent Space. AWS DevOps Agent connects to LaunchDarkly’s hosted MCP server as a client, giving it the ability to query flag state, read targeting rules, and list flags by project or environment.
Step 4 — Register the LaunchDarkly MCP server (account-level). MCP servers are registered at the AWS account level and shared among all Agent Spaces in that account.
Step 4a — Configure the authorization flow
LaunchDarkly’s hosted MCP server uses OAuth for authentication:
Step 4b — Review and submit
Step 5 — Add the MCP server to your Agent Space
After the account-level registration, connect it to your specific Agent Space:
Step 5 — Validate the connection. Run a test query to confirm the integration is working. In the DevOps Agent console, start a new investigation or chat session and ask: “List the feature flags in the <your-project-key> project in the production environment.” If the agent returns flag data from LaunchDarkly, the connection is active.
The automated experimentation lifecycle operates as a closed loop. A team states an improvement goal, and the system moves through a continuous cycle: decide what to try next, implement the change behind a feature flag, validate and deploy it, run an experiment to measure impact, roll it out safely, and feed the outcome back into the next iteration. The loop continues until the goal is met or the team decides to stop.
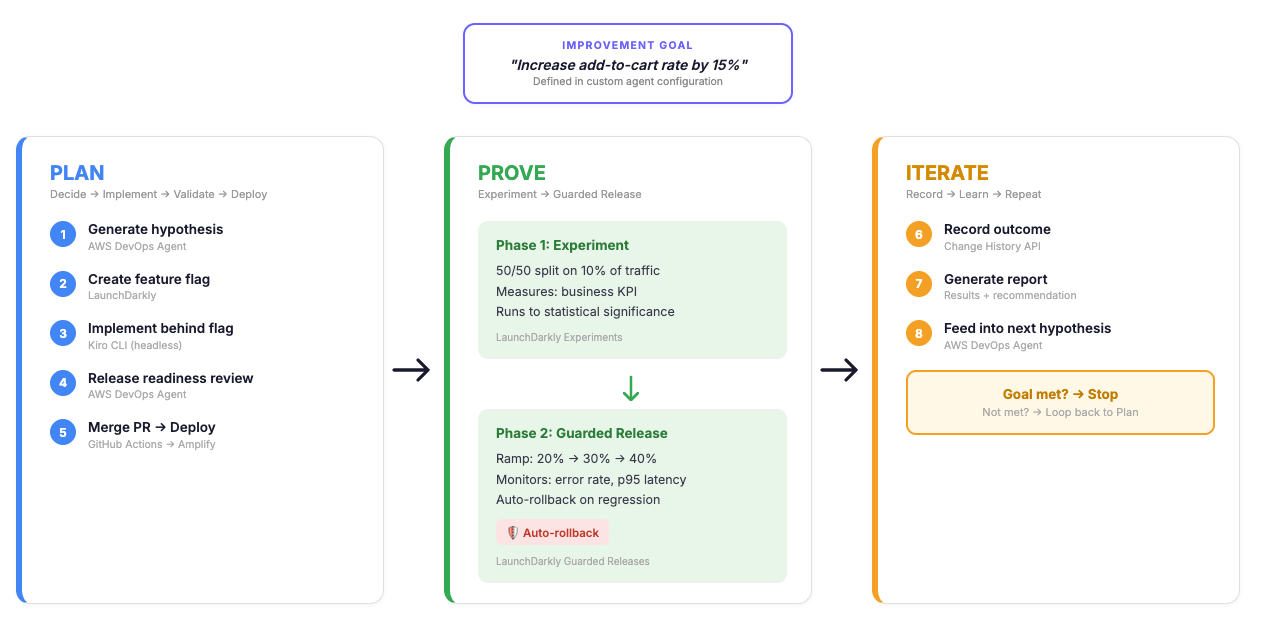
End-to-end Plan-Prove-Iterate workflow showing how AWS DevOps Agent orchestrates hypothesis generation, feature-flagged implementation, experimentation, guarded rollout, and outcome recording in a continuous improvement loop.
Each component has a distinct responsibility. AWS DevOps Agent orchestrates the cycle: it runs on a schedule as a Custom Agent which is a user-defined agent with its own instructions, skills, and connected tools that executes autonomously without pausing for input unless something fails. AWS DevOps Agent supports Custom Agents as a way to encode a specific workflow, including its decision logic, safety constraints, and cadence, into an agent that runs end-to-end on its own. In this solution, the Custom Agent reviews goals, generates hypotheses informed by prior outcomes, coordinates implementation and validation, and drives iteration across multiple experiment cycles.”. Kiro CLI runs in headless mode inside the Experiment MCP Server container on Amazon Bedrock AgentCore, implementing code changes behind LaunchDarkly feature flags and opening pull requests without a human operating an IDE.
LaunchDarkly hosts feature flags, experiments, and Guarded Releases, monitors metrics in real time, and reverts flag state when a threshold is breached. It also exposes a hosted MCP server with tools the agent calls directly. The Experiment MCP Server (custom, built for this solution) exposes the remaining operations over MCP: code implementation through Kiro, PR merge, and deployment triggering.
The agent acts as an MCP client connected to these two servers. LaunchDarkly’s hosted MCP server provides flag management, experiment lifecycle, Guarded Release, and observability tools. The Experiment MCP Server provides code implementation, PR merging, and deployment tools. This design separates decision-making from execution: the agent decides what to do, the MCP servers handle how.
The lifecycle operates in three phases.
Plan — The agent decides the next action for a goal, generates a hypothesis informed by prior outcomes when iterating, and creates a feature flag in LaunchDarkly. It then invokes Kiro CLI to implement the change behind the flag and open a pull request. AWS DevOps Agent validates the change through release readiness review. After a green review, the PR is merged and a GitHub Actions workflow deploys the application through AWS Amplify.
Prove — Two sequential phases run after deployment. First, a 50/50 experiment splits 10% of traffic on a business KPI (for example, add-to-cart rate) until statistical significance selects a winning variation. Then a Guarded Release ramps the winning variation from 20% to 30% to 40% and eventually to 100% while LaunchDarkly monitors operational guardrails (error rate, page-load-time-p95). If a guardrail threshold is breached, LaunchDarkly reverts the flag state automatically, requiring no redeployment. The experiment measures value (does the change improve the goal metric?); the Guarded Release measures safety (does the change hold up at scale?).
Iterate — After a rollout concludes, the agent queries LaunchDarkly’s Change History API to associate specific flag modifications with outcomes. The recorded outcome informs the next hypothesis, and the cycle repeats until the goal is met or the agent recommends waiting.
AWS DevOps Agent reads code, reviews changes, and decides what to do next. It does not take action on its own. To move from decision to execution, you connect it to MCP servers that expose operations as tools.
LaunchDarkly’s hosted MCP server covers flags, experiments, and Guarded Releases. We needed operations it doesn’t cover — writing code, merging PRs, and deploying — so we built the Experiment MCP Server. It runs on Amazon Bedrock AgentCore and exposes five tools: create_task and get_task_status (invoke Kiro CLI to implement changes and open a PR), merge_pr, trigger_deployment, and get_deployment_status.
These are mutation operations. When the agent calls create_task, Kiro writes real code. When it calls merge_pr, that code lands in main. You are responsible for this server — what it exposes, which repos it can touch, which branches it can merge to. We scoped ours to one repository, one branch, and one Amplify application. Those constraints live in the MCP server’s code, not the agent’s prompt, because API-level scoping cannot be misinterpreted.
The Experiment MCP Server [CG1] is a Python application built on FastMCP, packaged as a container and deployed to Amazon Bedrock AgentCore over stateless HTTP so the platform can restart or replace the container without breaking in-flight requests. At startup, the container pulls credentials from AWS Secrets Manager, clones the target repository, and makes Kiro CLI available as a local binary. This single-container design keeps everything colocated: when the agent calls create_task, the server spawns Kiro CLI as a headless subprocess with direct filesystem access to the cloned repo rather than making a network call to a separate code-generation service. Kiro CLI receives a structured prompt containing the task description, the LaunchDarkly flag key, and the variation details, then writes the change, commits to a new branch, and pushes. The server opens a pull request through the GitHub API and returns the task ID immediately without waiting for Kiro to finish. The caller polls get_task_status, which long-polls against an S3-backed state store so task progress survives container restarts. Deployment tracking follows a similar pattern: trigger_deployment dispatches a GitHub Actions workflow and returns the real GitHub run ID, and get_deployment_status reads live status directly from GitHub, so there is nothing to lose if the container cycles between calls. The overall design principle is that the MCP server coordinates work and delegates persistence to external systems (S3 for task state, GitHub for deployment state, Secrets Manager for credentials) rather than holding anything in memory that a restart would erase.
The agent runs on a schedule. Each run, it evaluates the current state of each goal and picks one of three actions: create a new experiment (no active rollout exists), iterate on a prior result (a rollout completed and the goal is not yet met), or wait (an experiment or rollout is still in progress).
The entry point for the system is an outcome, not a task list. The team picks a business metric from the available set — add-to-cart rate, checkout conversion, bounce rate, or page-load-time-p95 — and sets a target improvement, for example “increase add-to-cart rate by 10%.” Error rate is reserved as a safety guardrail during the Guarded Release phase and cannot be chosen as the primary success metric, because the system needs an independent operational signal to decide whether a winning variation is safe to scale. Beyond the metric and the target, all other inputs are optional. The agent infers the current baseline, the areas of the application in scope for changes, and any constraints from the codebase and production data. If those assumptions are off, the team corrects them before any code is written. The team states where they want to end up, and the agent works backward from there.
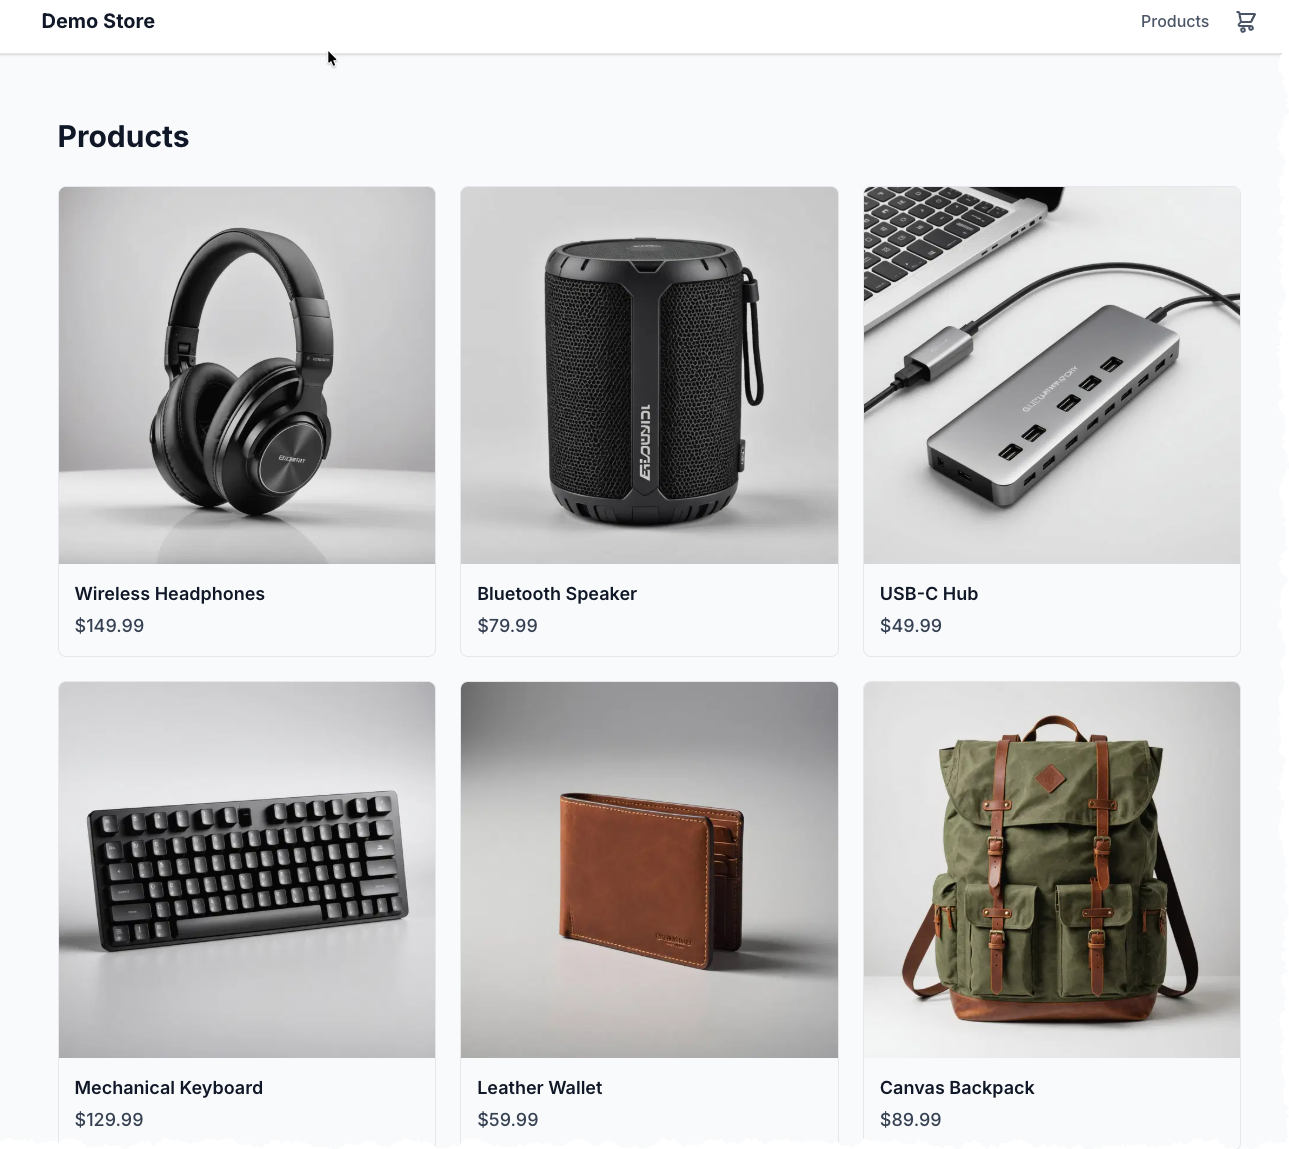
Demo Store product listing page used as the test surface for the add-to-cart experimentation cycles. Product cards currently show the control layout (no inline Add to Cart button).
For new goals, the agent explores the target repository and proposes a code change likely to move the metric. For iterations, it reads prior outcomes and adjusts its approach based on what worked and what did not. Before any code change, the agent creates a feature flag in LaunchDarkly (boolean, OFF by default, named with a convention like exp-add-to-cart-*) so every change ships behind a flag from the start.
Implementation runs through Kiro CLI in headless mode. The agent calls create_task, Kiro clones the repository, writes the change behind the feature flag, and opens a pull request.
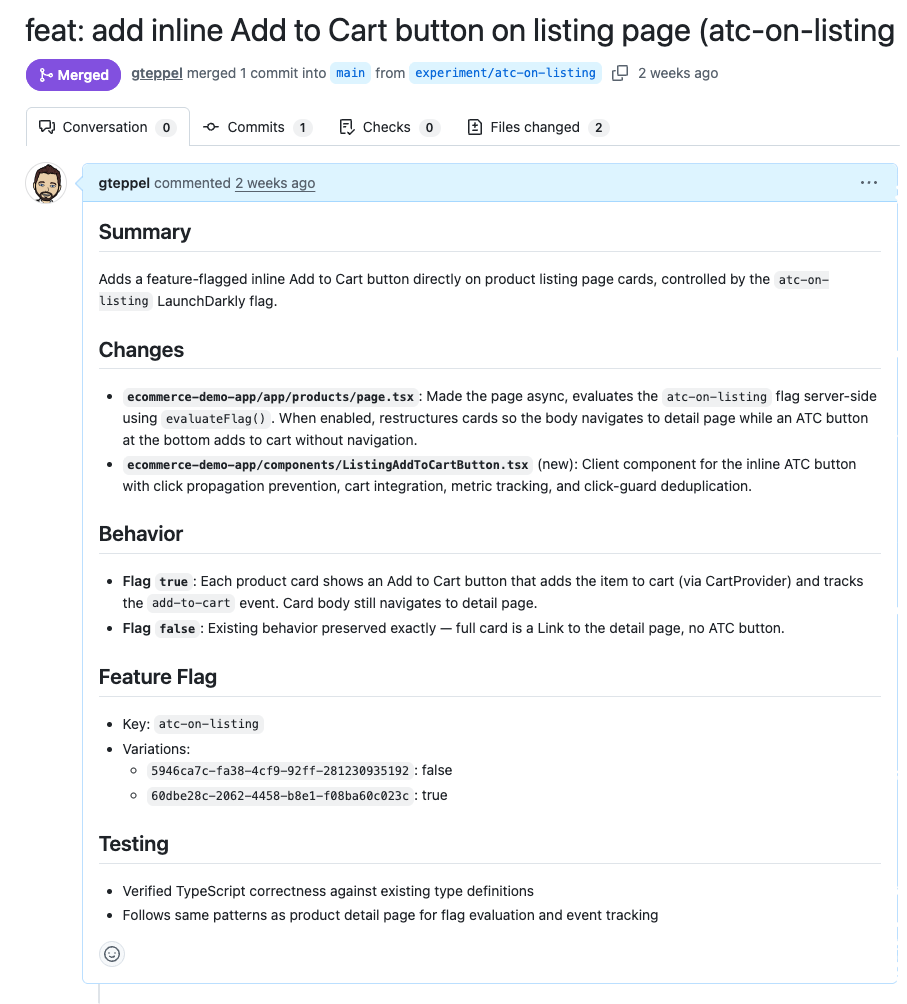
Merged GitHub PR implementing the feature-flagged inline Add to Cart button on the product listing page, controlled by the atc-on-listing LaunchDarkly flag.
AWS DevOps Agent then runs a release readiness review on the PR. If the review fails, the agent retries up to three times before stopping to ask for help. After a green review, the PR is merged and a GitHub Actions workflow deploys through AWS Amplify.
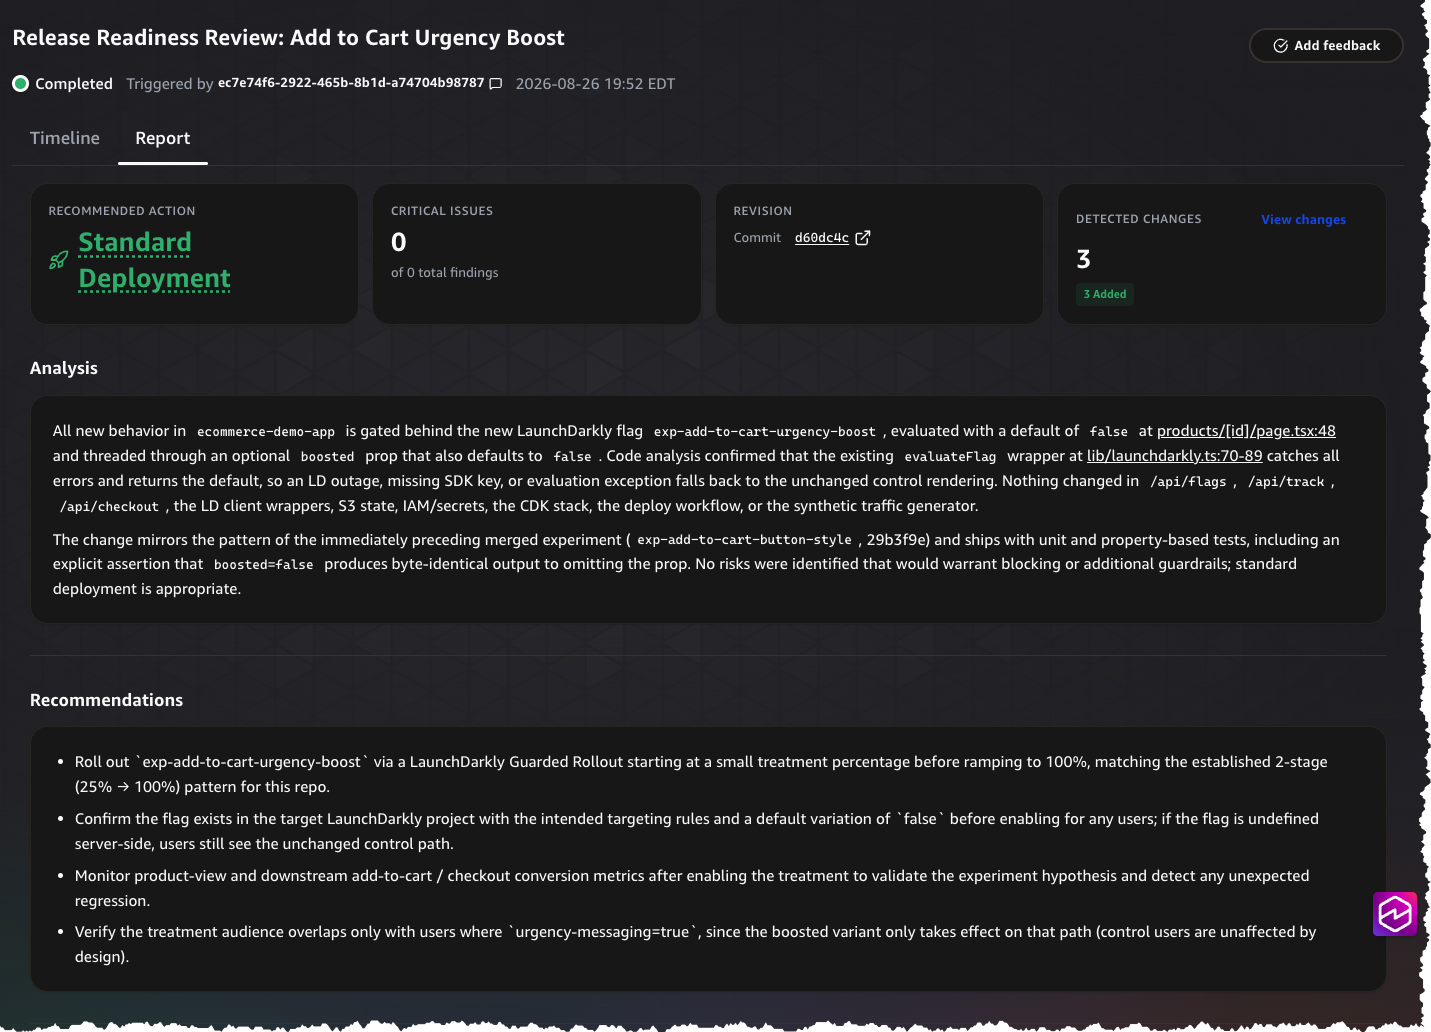
AWS DevOps Agent Release Readiness Review for the Add to Cart Urgency Boost experiment. The automated review found zero critical issues and recommended standard deployment with a guarded rollout.
Once deployed, the flag is toggled on and the experiment begins. The agent creates a 50/50 experiment across 10% of traffic, splitting on the goal’s business KPI. In production, experiment data comes from real users interacting with your application, with metrics emitted through OpenTelemetry to LaunchDarkly. For this reference implementation, we built a synthetic traffic generator that simulates user sessions across both treatment and control variations, producing the conversion events and operational metrics that drive experiment decisions. It runs alongside the demo application and generates enough volume to reach statistical significance within minutes rather than days. The synthetic traffic generator is a demo convenience, not a production requirement. Any application that emits the right events to LaunchDarkly will work with this architecture.
The agent checks for results on each Custom Agent execution until statistical significance is reached. In an interactive chat session, you prompt the agent to check when you are ready. If the treatment wins, the agent proceeds to the Guarded Release. If it loses, the agent archives the flag and records the outcome for the next iteration.
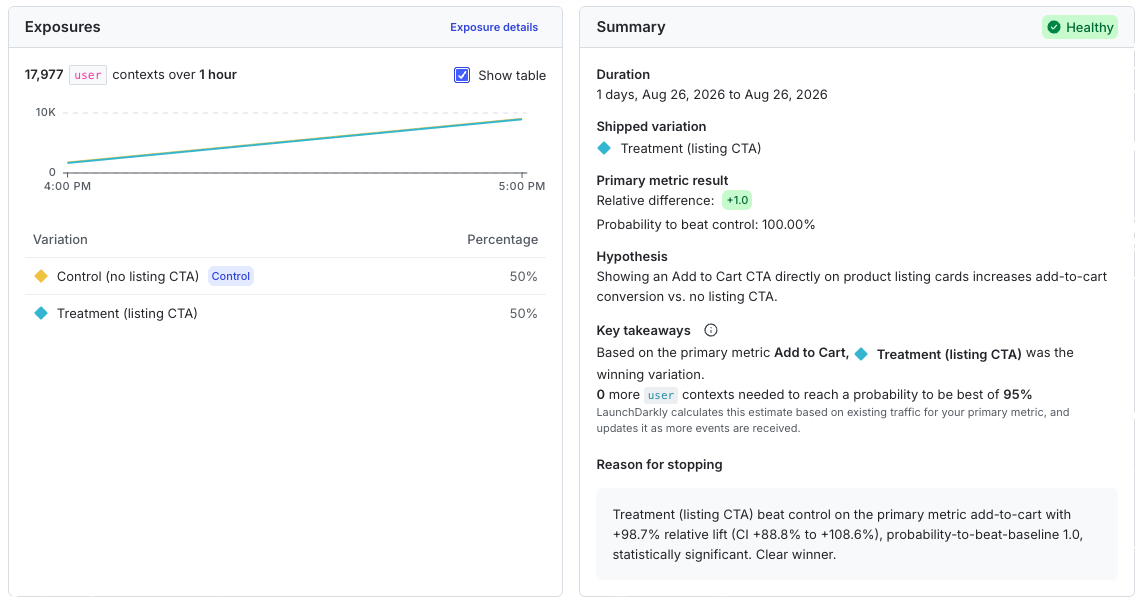
LaunchDarkly experiment summary for the inline Add to Cart listing CTA test. Treatment won decisively with 98.7% relative lift in add-to-cart conversion and 100% probability to beat control.
The Guarded Release ramps the winning variation from 20% to 30% to 40% while LaunchDarkly [1] applies sequential testing to the operational guardrail metric, halting the rollout as soon as the data shows a statistically significant regression against the original variation.. If a guardrail threshold is breached at any stage, LaunchDarkly reverts flag state at runtime without a redeployment. Guarded Releases and automatic rollback serve as the runtime safety net: if something goes wrong after deployment, the system reverts flag state without waiting for a human to intervene.
To validate the safety net in the reference implementation, we triggered a simulated error-rate spike during the ramp. LaunchDarkly detected the regression within the monitoring window, halted the rollout, and reverted the flag to its pre-rollout state automatically. No human intervened, no redeployment ran, and the application returned to the control behavior within seconds. The screenshot below shows the Guarded Release dashboard after the rollback.
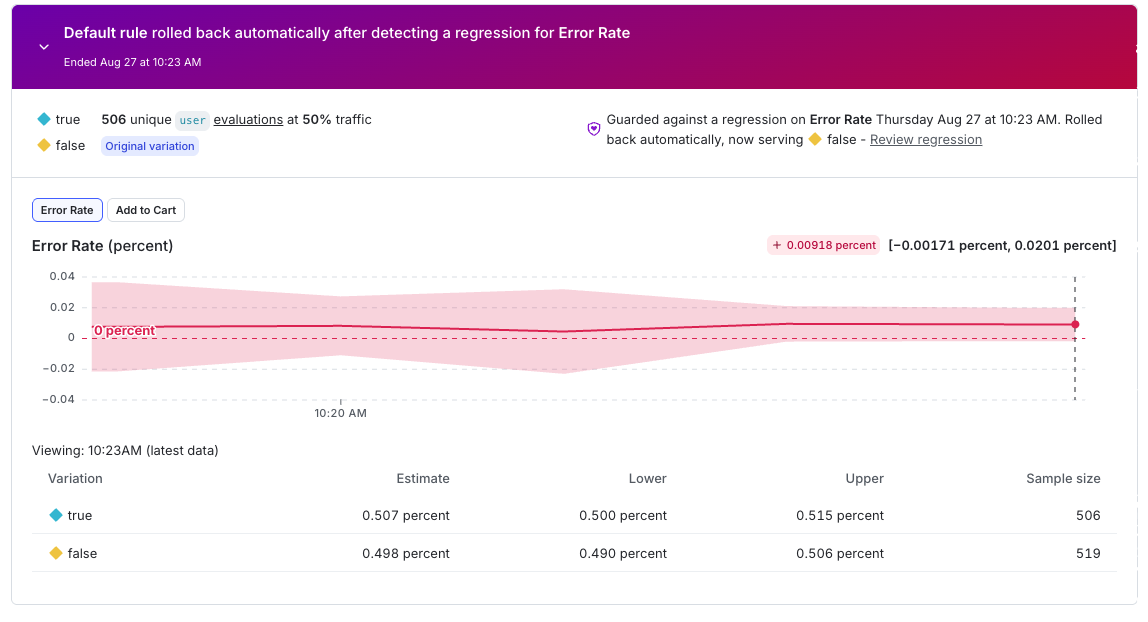
LaunchDarkly Guarded Release auto-rollback event. The system detected an error rate regression during the ramp phase and automatically rolled traffic back to the control variation.
After recording the rollback and feeding the outcome into the next iteration, the agent adjusted its approach and proposed a revised implementation that avoided the latency regression. The second attempt followed the same pipeline: hypothesis, feature flag, implementation, review, deployment, experiment, and Guarded Release. This time, monitoring completed with no regressions detected. LaunchDarkly rolled the winning variation forward to full traffic, with add-to-cart conversion lifting from 20.1% to 37.9% across the treatment population, confirming the experiment result held at scale.
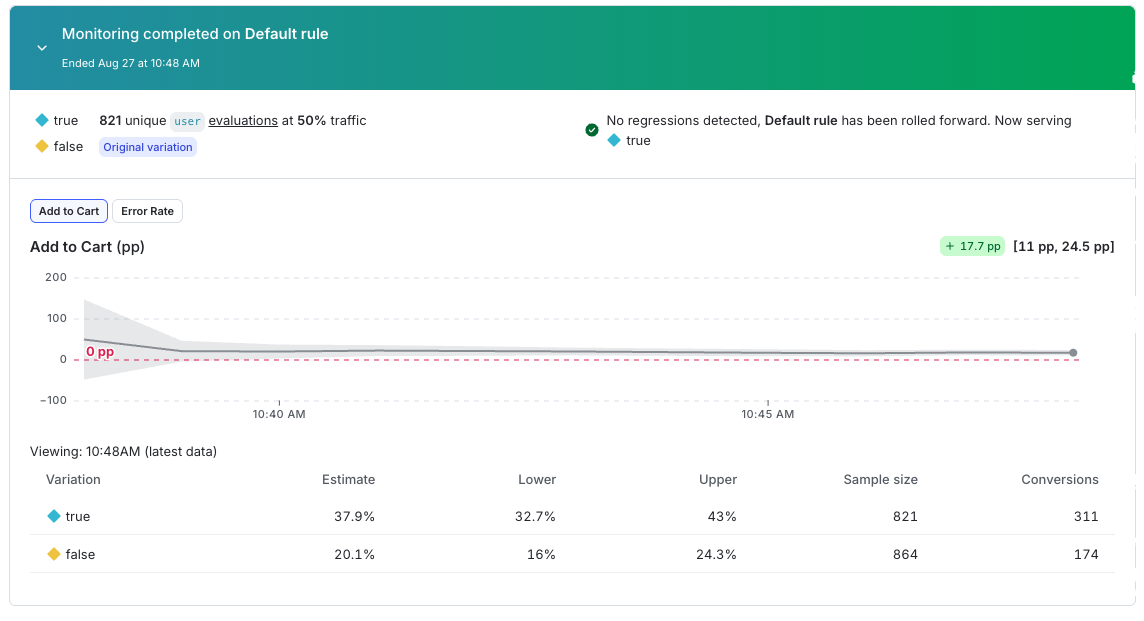
LaunchDarkly Guarded Release monitoring completion. The Add to Cart metric showed a 17.7 percentage point lift with no regressions, so the system graduated the treatment to 100% of traffic.
After each cycle, the agent generates a report documenting the hypothesis, experiment results, rollout outcome, and a recommendation for the next iteration. This report feeds into the next decision, so no context is lost between cycles.
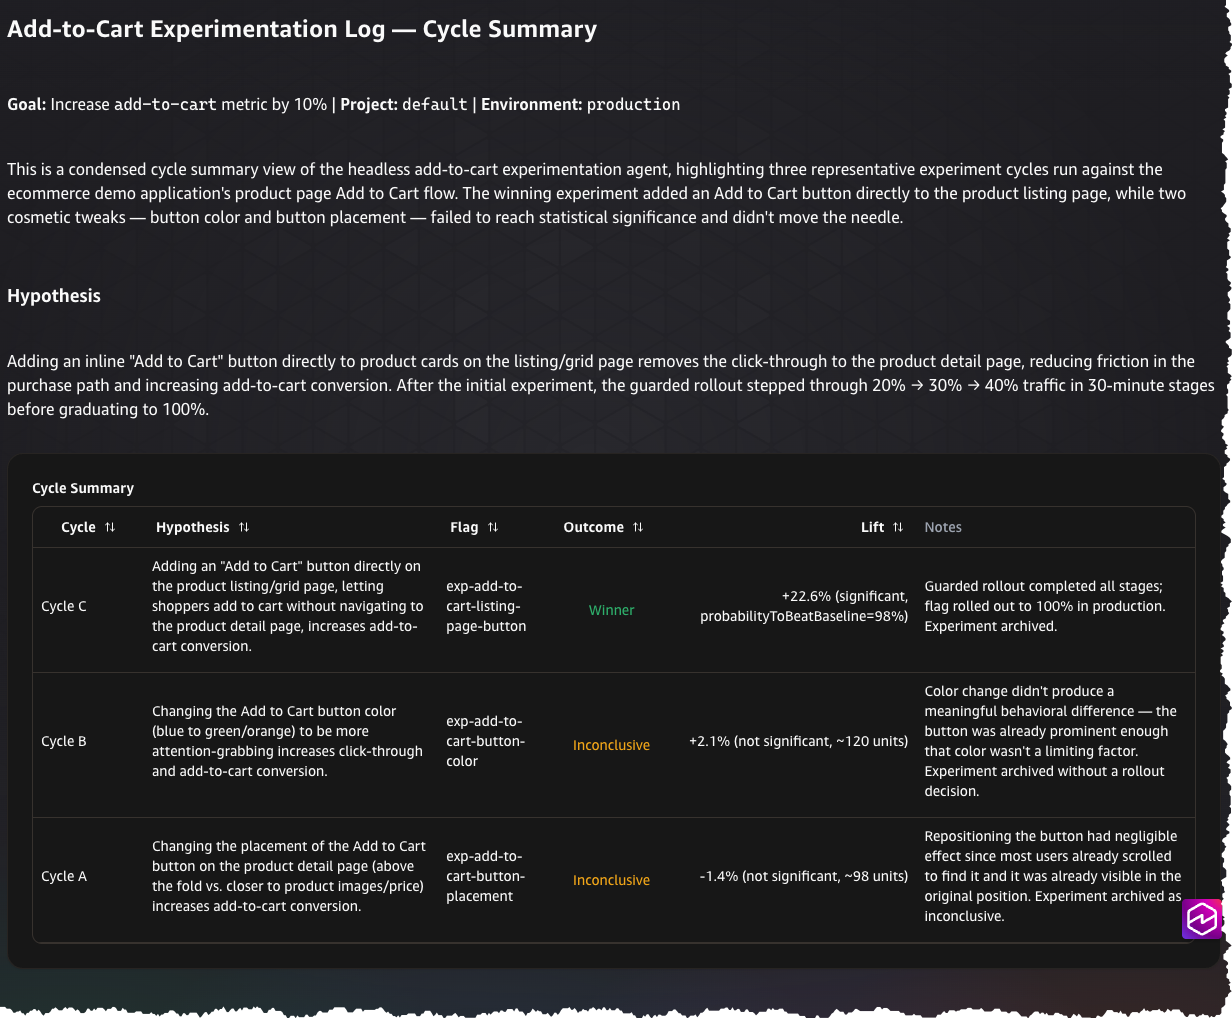
Experimentation cycle summary showing three hypothesis-test iterations. Only Cycle C (inline Add to Cart on listing page) reached statistical significance and was promoted to production. The two cosmetic experiments (button color and placement) were inconclusive.
The system operates within defined constraints. The agent validates every change through release readiness review before merge. It creates a feature flag before writing any code, so every change can be toggled off without a redeployment. Guarded Releases enforce operational guardrails at runtime with automatic rollback. The agent retries failed validations up to three times, then stops and asks for help rather than proceeding. All credentials are stored in AWS Secrets Manager and referenced by name only, never exposed in agent logs or tool calls.
To implement this workflow, you need AWS DevOps Agent enabled in your AWS account, a LaunchDarkly account (start with a free 30-day AWS trial), and a target application and repository. The reference uses a Next.js app deployed through AWS Amplify. Experiments are available on every LaunchDarkly plan, including the free Developer plan. Guarded Releases, which automate progressive rollouts with automatic rollback, require a LaunchDarkly Enterprise plan with the Guardian add-on. Without Guarded Releases, the workflow still runs experiments and reports results. You manage the rollout manually instead. If your plan does not include Guarded Releases, update the agent skill definition below to remove the Guarded Release actions.
Setup requires three steps. First, add the LaunchDarkly remote MCP server to your AWS DevOps Agent space. Second, deploy the Experiment MCP Server container to an AgentCore runtime, storing API keys and tokens in AWS Secrets Manager. Third, create your custom agent with the orchestration skill. Use the experimentation skill in AWS DevOps Agent to guide you through defining goals, connecting the MCP servers, and writing the orchestration instructions. The full orchestration skill is included below.
---
name: "experiment-orchestration"
description: "Orchestrates automated experimentation lifecycle using LaunchDarkly Guarded Rollouts, an AI coding agent for implementation, and GitHub Actions for deployment."
---

# Automated Experimentation

Use this skill when you have a goal you want to move through experimentation (e.g., "increase checkout conversion by 15%", "decrease page load time by 20%").

**Core principle: experiment first, then guarded rollout.** Always prove a change on a small, fixed slice of traffic via an A/B experiment before ramping it up through a guarded rollout. Never start a guarded rollout blind — it exists only to scale a change the experiment has already shown to work.

**Execution mode:** once the goal is confirmed (Step 1), run Steps 2–8 end-to-end. Async operations (code implementation, release review, deployment, experiment monitoring, rollout monitoring) should be checked periodically, not tight-polled — see the waiting note in each step. Only stop and ask the user something if a step fails unrecoverably (repeated failed release reviews, deployment failure, or an inconclusive/losing experiment result).

**The final report (Step 8) is mandatory, not optional.** The moment an experiment or rollout reaches a terminal outcome — winner, loser, inconclusive, or rollback — produce the full report in the same turn you announce the outcome. Don't let a casual "it worked! ????" substitute for the structured report.

## Step 1: Goal Clarification

Before doing anything, get answers to:

1. **What metric measures success?** *(Required)* e.g. conversion rate, page load time, bounce rate. Reserve your error-rate metric as a safety guardrail — never use it as the primary success metric.
2. **What's the target improvement?** *(Required)* e.g. 15% increase, 200ms decrease.
3. **What's the current baseline?** *(Optional — infer from production metrics if not given)*
4. **What parts of the app are in scope?** *(Optional — infer from the codebase if not given)*
5. **Any constraints?** *(Optional)* e.g. no changes to the payment flow.

Questions 1–2 are required before proceeding; infer 3–5 where possible and confirm your assumptions with the user before implementing.

## Step 2: Hypothesis Generation

Explore the target repository/codebase to find a plausible change:

1. Search and read the relevant code paths.
2. Think through what UI/UX or logic change could plausibly move the chosen metric.
3. Check whether this hypothesis (or something close to it) has already been tried and failed — look at flag history or archived flags with similar naming. Avoid repeating a known failure.
4. Present the hypothesis to the user before proceeding, along with your reasoning and any inferred assumptions from Step 1.

**Before finalizing a flag key, check for collisions:** look up any candidate flag key first.
- Already fully shipped (100% one variation, no split) → already decided, pick a different hypothesis.
- Actively running an experiment → mid-flight, don't compete with it, pick a different hypothesis.
- Doesn't exist → safe to create.

## Step 3: Implementation

1. Create a boolean feature flag, OFF by default in all environments. Name it with a clear pattern like `exp-<metric>-<short-description>` (e.g. `exp-checkout-conversion-cta-color`), lowercase with hyphens, ~50 chars max.
2. Hand off implementation to your coding agent/tool of choice, with clear instructions to gate the change behind the exact flag key from step 1.
3. This step is asynchronous — check status periodically rather than looping tightly on it.
4. Once implementation completes, move to Step 4 with the resulting branch/PR. If it fails, report the error and stop.

## Step 4: Release Readiness

Run your standard release/risk review on the PR before merging.

- If it passes: merge the PR.
- If it fails: feed the review's specific feedback back into implementation and retry. Cap retries at a small fixed number (e.g. 3 attempts total) — if it still hasn't passed, stop and report the last failure to the user rather than retrying indefinitely.

*(If your environment genuinely has no review capability available — e.g., a fully unattended automation context — you can skip straight to merge, but treat that as a deliberate, narrow exception you call out explicitly, not a default. Skipping review removes your only gate against shipping broken code.)*

## Step 5: Deployment

Deployment typically won't fire automatically on merge if your workflow is manually-triggered (`workflow_dispatch`-only) — you'll need to trigger it explicitly.

1. Trigger the deploy workflow on the merge target branch. Treat "already an in-progress deployment for this ref" as expected de-duplication, not an error — don't re-trigger.
2. Poll for status, but let your polling tool's own internal long-poll do the waiting rather than looping tightly yourself.
3. Watch for a "stale" status specifically: if a deployment reports "running" for far longer than normal, cross-check the actual CI run history by commit SHA/timing before assuming it's still in progress — a background poll process may have died without updating the record.
4. **Trigger a deployment at most once per attempt.** If you're unsure whether a previous trigger succeeded, check status first — never re-trigger just because you're unsure.
5. On timeout: stop, check the CI run directly, report the situation, ask how to proceed.
6. On explicit failure: stop and report — do not proceed to the experiment.
7. On success: proceed immediately to Step 6.

## Step 6: Experiment Phase (fixed 10%)

Prove the change on a small, fixed slice of traffic. Do **not** start a guarded rollout here — that's Step 7, and only after this proves out.

1. Turn the flag ON.
2. Configure a fixed 50/50 split across 10% of traffic (a flat allocation, not a staged ramp) on your chosen randomization unit (typically "user"). The remaining 90% of traffic is excluded from the experiment entirely.
3. Create an experiment with:
   - Exactly one primary metric: the success metric from Step 1.
   - Guardrail metric(s): always include your error-rate metric; add a performance metric (e.g. p95 page load time) too if this is a performance-focused change.
   - Treatments: control (off) at 50%, treatment (on) at 50%, allocated to 10% of total traffic.
4. Start the experiment/data collection.
5. Move to Step 7 to monitor toward a decision.

## Step 7: Monitoring & Outcome

Check status periodically — don't tight-loop. In an interactive session, check once and report progress, then pick back up later. In an unattended/scheduled context, check once per invocation and persist your progress somewhere durable between runs.

**Phase 1 — Prove the experiment at 10% (gate before any rollout):**

Watch for statistical significance on the primary metric:

- **Significant + positive lift** → experiment proven. Stop the experiment iteration and move to Phase 2.
- **Significant + negative lift** → declare a loser, archive the flag, skip Phase 2, go straight to the Step 8 report.
- **No significance after a reasonable ceiling (e.g. 30 minutes)** → report "inconclusive, need more traffic" and stop; don't proceed to Phase 2.

Never declare a winner off a single data point or before your stats engine confirms significance.

**Phase 2 — Guarded rollout ramp (only after Phase 1 proves the change):**

Start a guarded rollout with:
- The winning ("on") variation as the test, the original as control.
- Same randomization unit as the experiment.
- **Exactly 3 monitored stages, capped well below 100%** — e.g. 20% → 30% → 40%, ~60 minutes monitoring each. Don't add a stage at or above 100%; Guarded-rollout implementations reject stages above 50% audience allocation, and the rollout auto-promotes to 100% itself once the final monitored stage completes cleanly — no explicit 100% stage needed.
- The same primary + guardrail metrics as the experiment, each configured to notify and auto-rollback on regression.

Track stage progression. If the rollout rolls back or stops at any point, treat it as a regression: declare failed, clean up the flag (deprecate/archive it), and go to the Step 8 report.

Once the final stage completes cleanly and auto-promotes to 100%, declare a winner and go to the Step 8 report.

**Retrying after a rollback:** a rollback isn't always caused by your monitored metrics genuinely regressing — it can also be triggered by an unrelated application error surfacing mid-ramp. Before blindly restarting after the user says they've fixed something:
1. Confirm the flag's current state (should be back to 100% control, nothing stuck mid-rollout).
2. Check the change history timing between "advanced to next stage" and "reverted." A rollback within seconds of advancing is inconsistent with a full metric-window regression and points to an external cause instead.
3. If the flag is cleanly reverted and the external cause is confirmed fixed, it's safe to restart the guarded rollout from scratch with the same parameters.
4. Don't silently retry without this check, and don't refuse to retry just because a prior attempt rolled back — a genuinely fixed external cause is a legitimate reason to retry. A metric-driven loser is not — don't retry that.

**On any terminal outcome, immediately produce the Step 8 report in the same turn** — a one-line "it worked!" note is fine as a lead-in, but the structured report must follow, not wait for a follow-up request.

## Step 8: Report

Runs automatically the instant Step 7 reaches a terminal outcome (winner + auto-promoted to 100%; loser; inconclusive; or rollback/failure). Use this exact structure:

```
## Experiment Report: [Goal Description]

**Date:** [YYYY-MM-DD]
**Goal:** [metric] [direction] by [target]%
**Status:** [achieved / in progress / stalled]

### Hypothesis
[What we tried and why]

### Implementation
- Flag: [flag_key]
- Files modified: [list]
- Branch: [branch name]

### Release Readiness
- [reviewed, passed after N attempt(s) / skipped, per your environment's process]

### Experiment Phase (10% fixed split)
- Status: [proven / loser / inconclusive]
- Duration: [time]
- Metric change: [before] → [after] ([+/-]%)
- Statistical significance: [value, confidence interval]

### Guarded Rollout Phase (if reached)
- Status: [completed / rolled_back / not started]
- Duration: [time]
- Stages reached: [N of 3 monitored stages]
- If rolled back and retried: [root cause, outcome of retry]

### Safety Metrics
- error-rate: [baseline] → [final] ([no regression / regression detected])
- [other guardrails]: [baseline] → [final] ([status])

### Next Steps
[What to do next based on the outcome]
```

## Safety Rules (the non-negotiables)

- Always present the hypothesis before implementing.
- Always run a release/risk review before merging, unless your environment has a deliberate, explicitly-called-out exception.
- **Always prove a change via a fixed small-percentage experiment before starting any guarded rollout** — never ramp blind.
- Always include an error-rate (or equivalent "don't break prod") metric as a guardrail, separate from your success metric.
- Add a performance guardrail (e.g. p95 latency) for performance-focused changes.
- Every rollout metric should be configured to both notify AND auto-rollback on regression — don't rely on notification alone.
- **Cap guarded rollout stages well below 100%** (most platforms reject stages ≥50% audience allocation) and let the platform auto-promote to 100% after the final stage — don't try to add an explicit 100% stage.
- Distinguish a metric-driven rollback (don't retry) from an external-cause rollback (safe to retry once fixed) before restarting a rolled-back rollout.
- The final report is automatic and mandatory on every terminal outcome — never defer it to a follow-up ask.
This post described how AWS DevOps Agent, Kiro CLI, and LaunchDarkly connect into a closed-loop system that turns an improvement goal into a series of measured, safe experiments. The agent runs autonomously on a schedule: it generates hypotheses informed by prior outcomes, creates feature flags before any code change, invokes Kiro CLI in headless mode to implement changes behind those flags, validates through release readiness review, deploys through GitHub Actions and AWS Amplify, and hands off to LaunchDarkly for experiment measurement and guarded rollout. If a guardrail is breached at any point during the rollout, LaunchDarkly reverts flag state at runtime without a redeployment. After each cycle, the agent records what happened and feeds it into the next decision.
This directly addresses the three barriers that slow experimentation:
● Planning cost is reduced because the agent handles hypothesis generation, flag creation, implementation coordination, and validation. The team defines the goal; the system handles the wiring.
● Measurement disconnected from action is addressed because LaunchDarkly monitors metrics in real time and reverts flag state automatically when a guardrail is breached, requiring no redeployment and no waiting for a human to notice.
● Stalled iteration is solved because every outcome is recorded and fed into the next hypothesis automatically. The system does not forget what it learned, and it does not stall between iterations.
The architecture is available to implement today as a reference. The orchestration skill included in this post encodes the full 8-step workflow: goal clarification, hypothesis generation, implementation, release readiness, deployment, experiment, monitoring, guarded rollout, and reporting. Teams define their improvement goal, connect the LaunchDarkly MCP server and the Experiment MCP Server to a DevOps Agent custom agent, and let the system iterate toward the target within the safety boundaries they configure. A more turnkey experience is planned for the future.
Post Syndicated from jzb original https://lwn.net/Articles/1090824/
Inside this week’s LWN.net Weekly Edition:
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/kiycTWuIKI8
Post Syndicated from Explosm.net original https://explosm.net/comics/final-fantasy
New Cyanide and Happiness Comic
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3531
Не мога да спя и мисля глупости, и се ядосавам, щото someone is wrong on the internet. Тия дни четох нещо много полезно по темата за “това е просто инструмент”, и имам малко мисли по темата (писанието е доста по-добро от моето, ама имам нужда и аз да напиша нещо).
Първо, това е thought-terminating cliche – хората го казват като приключващо спора, колкото и глупаво и малоумно да е. Нито един инструмент не е “просто” инструмент – всеки инструмент носи със себе си допълнителни последствия, и има ефекти в/у нас и светът около нас, колкото и да си затваряме очите.
Преди да стигна до текущия “просто инструмент”, мога да дам няколко супер очевидни примера за “просто инструменти”, които имат много по-голямо влияние от базовата си функция.
Колите са един такъв прост и очевиден пример – основната им функция е транспортна, но на практика имат огромно влияние върху здравето (замърсяване и катастрофи), архитектурата на градовете, сегрегацията (в щатите са я докарали до наука, как да държим по-тъмнозелените надалеч, като направим така, че за тях няма транспорт), и т.н., и т.н..
Друг прост пример са оръжията и парите, които са различно регулирани на различни места. И за двете има политически течения, дето твърдят, че това са просто инструменти, но да отречем тяхното огромно влияние би било чак смешно.
И сега имаме някакви нови неща. Например, интернетът навсякъде, който също има огромно влияние. И който също е просто инструмент, който обаче с малко добавки почна да има сериозна роля в резултатите от различни избори по света, като един от по-крайните ефекти. После, bitcoin и подобните валути, които много улесниха прането на пари и разни незаконни разплащания, както и дадоха нов живот на стари схеми за измама. И сега AI, което за всичкия ток, който харчи, върши смислена работа на сравнително малко хора (не броя тия, дето усилено работят да издоят всичките пари на тоя свят, само за потребителите му), но се промотира като наследник на нарязания хляб и топлата вода.
Та, следващия, който тръгне да ми обяснява за как AI (или каквото и да е) е “просто инструмент”, ще му обясня, че и псуването на майка е просто инструмент и това, че го пращам да се съвокуплява с нея си е част от инструмента и няма що да се ядосва. В крайна сметка, той и хероинът е едно просто обезболяващо, къде ни е проблема…
Post Syndicated from Vic A original https://www.servethehome.com/update-on-risc-v-standards-and-adoption-at-hot-chips-2026/
At Hot Chips 2026, we got an update on RISC-V standards and adoption as RVA23 has become the new standard
The post Update on RISC-V Standards and Adoption at Hot Chips 2026 appeared first on ServeTheHome.
Post Syndicated from Shubham Purwar original https://aws.amazon.com/blogs/big-data/query-amazon-s3-tables-from-amazon-emr-trino-using-the-iceberg-rest-endpoint/
Organizations running analytics on Amazon Simple Storage Service (Amazon S3) data lakes often struggle with the operational overhead of managing Apache Iceberg tables, including compaction, snapshot expiration, and metadata tracking, while still needing fast, interactive SQL access across large volumes of data. Amazon S3 Tables, a capability of Amazon S3, addresses this by providing a purpose-built storage layer with native Apache Iceberg support and automated table maintenance. When you query S3 Tables from Amazon EMR using Trino and the Iceberg REST endpoint, you get a fully managed, open-standards-based analytics stack without the undifferentiated heavy lifting of table upkeep.
When paired with Amazon EMR running Trino, organizations gain access to a high-performance distributed SQL query engine capable of processing large-scale datasets. Trino’s ability to query data across multiple sources, combined with the automated optimization features of S3 Tables, creates a flexible analytics platform. The integration uses Apache Iceberg’s REST catalog specification, providing a standardized interface that supports compatibility across different compute engines while maintaining full control over query execution and data processing logic.
This architectural pattern is particularly valuable for organizations seeking to modernize their data platforms without vendor lock-in, as it relies on open standards and formats. The solution delivers high-throughput query performance with distributed SQL execution while significantly reducing the operational burden of managing table metadata, compaction, and snapshot lifecycle management. In this post, we show you how to create and query Amazon S3 Tables using Trino on Amazon EMR through the Apache Iceberg REST catalog endpoint.
This implementation demonstrates a complete integration between the Trino distribution on Amazon EMR and Amazon S3 Tables through the Apache Iceberg REST catalog endpoint. The architecture uses several key AWS services working in concert:
Amazon EMR serves as the managed compute layer, providing a scalable Hadoop framework that hosts the Trino query engine. Amazon EMR handles cluster provisioning, configuration management, and automatic scaling, allowing teams to focus on analytics rather than infrastructure management.
Apache Trino acts as the distributed SQL query engine, offering ANSI SQL compatibility and the ability to process queries across massive datasets with low latency for interactive workloads. Its connector architecture supports integration with various data sources, including the Iceberg REST catalog.
Amazon S3 Tables provides the storage and catalog layer, managing Apache Iceberg tables with built-in optimization. The service automatically handles compaction, snapshot expiration, and metadata management, reducing operational overhead while maintaining query performance. S3 Tables exposes a REST API endpoint that conforms to the Apache Iceberg REST catalog specification, which provides standardized integration with any Iceberg-compatible engine.
Apache Iceberg REST endpoint serves as the communication protocol between Trino and S3 Tables. This RESTful interface handles catalog operations including namespace management, table creation, metadata retrieval, and transaction coordination. The endpoint supports AWS Signature Version 4 authentication for secure access to table resources.
The data flow follows this pattern: Users submit SQL queries through the Trino CLI or JDBC interface. Trino’s Iceberg connector communicates with the S3 Tables REST endpoint to retrieve table metadata and plan query execution. The query engine then reads data directly from S3 using optimized file formats (Parquet, ORC) while using Iceberg’s metadata layer for partition pruning and predicate pushdown. Write operations follow a similar path, with Trino coordinating with S3 Tables to commit new data files and update table metadata atomically.
This architecture delivers several key benefits: separation of compute and storage for independent scaling, automated table maintenance reducing operational costs, open-source format compatibility preventing vendor lock-in, and fine-grained access control through AWS Identity and Access Management (IAM) and AWS Lake Formation integration.
Figure 1: Solution architecture for querying Amazon S3 Tables from Trino on Amazon EMR
Before getting started, make sure that you have the following:
For this post, we create the solution resources in the US East (N. Virginia) Region (us-east-1) using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.
Note: Querying Amazon S3 Tables through Trino on Amazon EMR requires Trino version 475 or later, available in Amazon EMR 7.11 and later.
In this post, you use the CloudFormation template emr-trino-s3tables.yaml.
To create the solution resources, complete the following steps:
emr-trino-s3tables.yaml using the CloudFormation template.
| Parameters | Description | Sample value |
| Stack Name | Name of CloudFormation stack | emr-s3tables-trino |
| VPC CIDR block | IP range (CIDR notation) for this VPC. | 10.0.0.0/16 |
| Private Subnet CIDR block | IP range (CIDR notation) for the private subnet in the second Availability Zone. | 10.0.1.0/24 |
| Resource name Prefix | Short prefix applied to every resource name | emr-s3tables |
| S3 Tables bucket name | Name of S3 table Bucket | trinoemrs3tablebuck |
| EMR release | Release version of Amazon EMR | EMR 7.12 |
The stack creation process can take approximately 15 minutes to complete. You can check the Outputs tab for the stack after the stack is created, as shown in the following screenshot.
Figure 3: CloudFormation stack outputs
The CloudFormation template performs several key tasks:
The CloudFormation template automatically configures the S3 Tables catalog in Trino on Amazon EMR. In the next section, we examine the configuration that drives this integration.
A catalog in Trino on Amazon EMR is the configuration that grants access to a specific data source. Each Trino on Amazon EMR cluster can have multiple catalogs configured, allowing access to different data sources simultaneously.
As part of this setup, the CloudFormation template creates a catalog properties file at /etc/trino/conf/catalog/s3tables_irc.properties with the following configuration:
The following table lists the key properties in the catalog configuration on Trino:
| Property name | Description |
| iceberg.rest-catalog.uri | REST server API endpoint URI (necessary). |
| iceberg.rest-catalog.warehouse | Warehouse ID or location for the catalog (necessary). For S3 Tables, this is the ARN for the S3 table bucket as shown in the preceding properties example. |
| iceberg.rest-catalog.sigv4-enabled | Must be set to ‘true’ (necessary) |
| iceberg.rest-catalog.signing-name | Must be set to ‘s3tables’ (necessary) |
| iceberg.rest-catalog.view-endpoints-enabled | Must be set to ‘false’ (necessary) |
| fs.hadoop.enabled | Must be set to ‘false’ |
| fs.native-s3.enabled | Must be set to ‘true’ |
| s3.iam-role | Amazon Resource Name (ARN) of the IAM role with permissions to S3 Tables. In this post, we use the same role, which is the service role for Amazon EMR. |
| s3.region | AWS Region, for example us-east-1 |
This configuration establishes a connection between Trino and the S3 Tables REST endpoint. You can have multiple catalogs registered, one per S3 table bucket, which is determined by the iceberg.rest-catalog.warehouse property.
The Amazon EMR service role requires proper trust relationships to function correctly. Navigate to the IAM console and configure the trust policy for your Amazon EMR service role:
This trust policy establishes two critical relationships:
Now that you have Trino on Amazon EMR set up and configured to work with S3 Tables, you can explore how to work with this integration.
Navigate to Amazon EMR and select Connect to the primary node using AWS Systems Manager Session Manager for passwordless SSH.
Figure 4: Connecting to the primary node with Session Manager
When you’re connected, you can use the Trino CLI with your S3 Tables catalog:
This connects you to the Trino on Amazon EMR using the S3 Tables integration you configured.
Figure 5: Trino CLI connected to the S3 Tables catalog
In this section you run through some example queries to demonstrate the functionality.
First, you create a namespace (schema) in S3 Tables. A namespace in S3 Tables is a logical container or organizational unit that helps group related tables and objects together.
Create a table with various data types. You don’t need to specify the table type as Iceberg explicitly because you’re connecting to the Iceberg catalog. You can use all standard Iceberg capabilities, such as partitioning and sorting. Furthermore, some of the important Iceberg table properties that support table maintenance operations are configured with default values. You also have the option to edit the configurations using S3 Tables maintenance APIs.
Table property explanation:
format = 'PARQUET': Specifies Parquet as the file format for optimal compression and query performance.sorted_by = ARRAY['customer_id']: Defines sort order within data files, improving query performance for customer_id filters.Verify the table creation:
You should see customers in the output, confirming the table exists in the S3 Tables catalog.
You can insert some sample data into your table. You can also use an existing table in any of the catalogs configured in Trino on Amazon EMR to read data and write into the S3 table with an INSERT INTO ... SELECT statement.
This INSERT operation demonstrates Trino’s ability to write data to S3 Tables. Behind the scenes, Trino:
Execute a SELECT query to retrieve and verify the inserted data:
The query should return all eight customer records with proper formatting. You can also execute more complex analytical queries:
These queries demonstrate Trino’s SQL capabilities and the integration with S3 Tables for both read and write operations.
S3 Tables with Iceberg provides several features for data management:
Step 1: Check available snapshots.
Step 2: Query the table as of a specific snapshot.
To clean up the resources, navigate to CloudFormation and delete the stack that you created.
This solution demonstrates an integration between Amazon EMR Trino and Amazon S3 Tables using the Apache Iceberg REST catalog specification. In this post, we showed you how to create and query S3 Tables from Trino on Amazon EMR. The architecture delivers several advantages for modern data platforms:
Operational simplicity: S3 Tables eliminates the complexity of managing Iceberg table metadata, compaction schedules, and snapshot lifecycle policies. The service handles these operations automatically, allowing data teams to focus on analytics rather than infrastructure maintenance.
Performance at scale: The architecture is designed for large-scale workloads. Trino distributes query execution across the cluster while Iceberg’s metadata layer helps the engine locate only the relevant data files. Features like partition pruning, predicate pushdown, and columnar file formats can help improve performance for both interactive and batch workloads.
Cost efficiency: This architecture separates compute and storage, so you can scale each independently based on workload requirements. S3 Tables automatically compacts small files to help reduce storage overhead, and Amazon EMR clusters can scale dynamically so you pay for compute only when needed.
Open standards and portability: By using Apache Iceberg’s open table format and REST catalog specification, this solution avoids vendor lock-in. Other Iceberg-compatible engines can access tables created in S3 Tables including Apache Spark, Apache Flink, and Dremio, providing flexibility in tool selection.
Fine-grained access control: Integration with IAM and resource-based policies provides access control at the table bucket, namespace, and table level. For fine-grained access at the column and row level, you can integrate with AWS Lake Formation. AWS Signature Version 4 authentication supports secure communication between Trino and S3 Tables.
ACID transactions: Iceberg’s transaction model guarantees atomicity, consistency, isolation, and durability for all table operations. This supports reliable concurrent reads and writes, making the platform suitable for production workloads requiring data consistency.
This architectural pattern is particularly well-suited for organizations building modern data lakehouses, migrating from traditional data warehouses, or consolidating multiple analytics platforms. The combination of the managed compute of Amazon EMR, Trino’s versatile query engine, and the automated table management of S3 Tables creates a strong foundation for data-driven decision making.
To learn more about the services and features discussed in this post, see the following resources: