Post Syndicated from Explosm.net original https://explosm.net/comics/opposable-thumbs
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/opposable-thumbs
New Cyanide and Happiness Comic
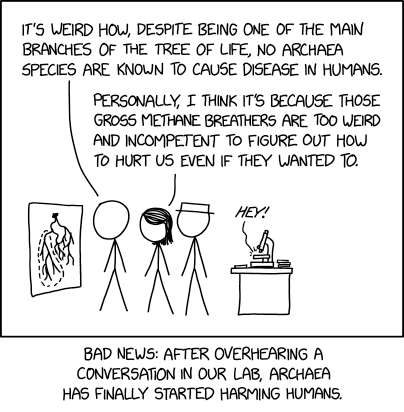
Post Syndicated from xkcd.com original https://xkcd.com/3095/
Post Syndicated from corbet original https://lwn.net/Articles/1022744/
Version
10 of the AlmaLinux OS distribution has been released.
The goal of AlmaLinux OS is to support our community, and AlmaLinux
OS 10 is the best example of that yet. With an unwavering eye on
maintaining compatibility with Red Hat Enterprise Linux (RHEL), we
have made small improvements to AlmaLinux OS 10 that target
specific sections of our userbase.
See the
release notes for details.
Post Syndicated from Max Peterson original https://aws.amazon.com/blogs/security/introducing-new-regional-implementations-of-landing-zone-accelerator-on-aws-to-support-digital-sovereignty/
Customers often tell me that they want a simpler path to meet the compliance and industry regulatory mandates they have in their geographic regions. In our deep engagements with partners and customers, we have learned that one of the greatest challenges for customers is the translation of security and compliance requirements into distinct technical controls. At Amazon Web Services (AWS), security is our top priority, and we understand that protecting your data in a world with changing regulations, technology, and risks takes teamwork. As we’ve said, security is foundational to sovereignty.
AWS helps organizations to develop and evolve security, identity, and compliance into key business enablers; that’s why we’re committed to working with national cyber authorities and regulators to help define and establish how their compliance standards can be translated into security best practices in the cloud. We’re responding to customer requests to create locally tailored approaches aligned to their own regional standards and guidance as established by in-region authorities.
Since its launch in 2022, Landing Zone Accelerator on AWS has been instrumental in helping thousands of customers deploy cloud foundations that align with multiple global compliance frameworks and AWS best practices, including the Baseline Informatiebeveiliging Overheid (BIO) in the Netherlands, and the Esquema Nacional de Seguridad (ENS) in Spain. AWS is committed to expanding our regional implementations to help customers meet specific national and regional standards and digital sovereignty goals.
In March, I was proud to share the news of the cooperation agreement between the Federal Office for Information Security (BSI) and AWS, where AWS committed to help advance digital sovereignty and cybersecurity best practices and standards in Germany and across the European Union. With that in mind, I’m excited to share that our next regional implementation of Landing Zone Accelerator on AWS will support customers with workloads in Germany. The C5-ready Landing Zone Accelerator is designed to help customers meet their Cloud Computing Compliance Criteria Catalogue (C5) compliance objectives in the cloud. This will be available to our customers in Q3-2025, and at launch, our regional implementations will also be available in AWS European Sovereign Cloud.
The C5 attestation scheme is backed by the German government and was introduced by the BSI in 2016. AWS has adhered to the C5 requirements since their inception. C5 helps organizations demonstrate operational security against common cybersecurity threats when using cloud services through the German government’s Security Recommendations for Cloud Computing Providers.
For many customers in Germany, adherence to C5 is a requirement, and this is evidenced through a compliance assessment by an authorized assessor. Preparing for this assessment is critical for a successful outcome and is why AWS has partnered with AWS Global Security & Compliance (GSCA) Partner Schellman to provide the assessor insight as to how the C5-ready Landing Zone Accelerator can accelerate and simplify the path to C5 adoption for AWS customers.
As one of the few firms with deep expertise and experience in C5 assessments, Schellman has completed several dozen evaluations across a wide range of clients—from agile startups to global enterprises. This diverse portfolio underscores Schellman’s capabilities, deep technical expertise, and unwavering commitment to security assurance.
“Our team has seen firsthand how the C5 standard fosters transparency and builds trust in cloud services. We’re proud to support our clients not just in understanding C5, but in strategically leveraging it to improve security and competitiveness on a global scale.”
Jeff Schiess, Managing Director, Schellman
Lowering the Barrier to Entry – Schellman recognizes that achieving C5 compliance can sometimes be intimidating, particularly for organizations new to the framework. To that end, Schellman has performed an assessment against the foundational infrastructure provided by LZA on AWS, designed to simplify the C5 journey. The LZA provides preconfigured infrastructure templates and security baselines that significantly reduce the complexity of establishing C5-compliant cloud environments.
“With the Landing Zone Accelerator, organizations can build on a C5-ready foundation right from the start. It’s a practical, scalable solution for companies that might otherwise find the C5 standard overwhelming.”
Kristen Wilbur, Principal, Schellman
Landing Zone Accelerator on AWS automatically implements hundreds of security capabilities that map to control requirements across geographic compliance frameworks. This saves customers hundreds of hours in planning and implementing secure networking and account configurations by providing them with a foundation based on the AWS Well-Architected Security Pillar and AWS security best practices. Meeting compliance requirements, having verifiable access controls and data transfer restrictions, independence and choice over the technology stack, and surviving large-scale disruptions are some of the key capabilities that customers require of a sovereign-by-design workload. However, for many customers, translating regulatory requirements into a set of discrete technical controls and applying them consistently across one or more AWS accounts and AWS Regions can be time-intensive and challenging.
We provide customers and partners with detailed guidance on how to configure Landing Zone Accelerator on AWS in accordance with their local security and compliance requirements, including digital sovereignty requirements. This includes control mapping to local regulations or policies that shows customers how controls implemented in a landing zone are mapped to the specific requirements, calling out where customers are required to do more to meet these as part of our shared responsibility model—this includes organizational policies and procedures where customers must implement additional controls within their application or workload to meet local requirements.
Landing Zone Accelerator on AWS provides customers with a choice of configurable preventative, detective, and proactive controls to help customers meet their data residency, security, and compliance objectives, whether you’re a public sector customer wanting to keep data in a single Region or navigating the complex needs of multi-national organizations with operations subject to differing digital sovereignty requirements.
Landing Zone Accelerator on AWS goes beyond just provisioning a secure, multi-account environment. It establishes a well-structured, multi-account architecture using AWS Organizations. This logically isolates workloads, management functions, and security controls into dedicated organizational units (OUs). This not only enhances security and operational efficiency, but also helps customers to enforce consistent data residency, access management, and compliance policies across their entire cloud footprint. These powerful guardrails empower customers to quickly harness the innovative potential of cloud technologies, whilst delivering business value from an established security and compliance baseline.
By providing this automated approach, AWS empowers organizations to rapidly deploy cloud environments tailored to their specific local requirements in days instead of weeks; with robust security, compliance, and operational guardrails in place from the outset. Landing Zone Accelerator on AWS is designed to simplify the path to cloud adoption and compliance for organizations, particularly those in regulated industries or with sovereignty requirements. This approach marks a shift from the previous heavy lift required for organizations to migrate workloads to the cloud while meeting their needs.
There is a lot of complexity involved with navigating the evolving digital sovereignty landscape—but you don’t have to do it alone. Our AWS Digital Sovereignty Competency connects customers with trusted partners with demonstrated expertise to advise and architect for their customers’ digital sovereignty needs while taking advantage of the full potential of the AWS Cloud. As part of the competency, AWS is supporting partners to navigate customer challenges across four pillars: data residency, data protection, access control, and survivability.
Customers have told me about how challenging it can be to architect to address their sovereignty needs, often requiring manual iteration and longer time to value. Using Landing Zone Accelerator on AWS is one of the ways AWS and AWS Partners can work together to address customers’ sovereignty needs with a repeatable approach that helps our customers and partners move faster. I’m excited by how regional implementations of Landing Zone Accelerator on AWS is helping AWS Sovereignty Partners, such as Atos and SVA, to move faster without compromise.
“Compliance with regulations like C5 is essential for customers in the public sector and regulated industries, who prioritize digital sovereignty, and this is central to our Cloud for Clinics initiative with AWS in the German Healthcare market. The availability of the C5 LZA significantly reduces the technical complexity, giving us a common technical platform to build on reducing time to market. Atos is driving the operational rollout and expanding the scope of compliance mappings to further streamline customer compliance. At the same time, we are incorporating essential managed services like SOC/SIEM which we believe will make compliant cloud adoption easier to drive innovation by the Public Sector, Healthcare institutions or customers in regulated industries like Financial Services and Utilities.”
Boris Hecker, Managing Director, ATOS Germany
“Compliance with BSI C5 criteria for customers from the public sector and regulated industries is a basic requirement for the use of public cloud services. Implementing the regulations is often complex, time-consuming and resource-intensive. For this reason, customers are looking for solutions that they can tailor to the specific requirements of their industry; while ensuring they meet compliance standards. SVA supports customers in maintaining the balance between innovation and compliance with customized, C5-certified, managed services. We rely on solutions such as the Landing Zone Accelerator on AWS to reconcile the use of market-leading public cloud infrastructure with regulatory requirements.”
Patrick Glawe, Hyperscaler Lead at SVA
For more information, see Landing Zone Accelerator on AWS and AWS Digital Sovereignty Competency Partners
Post Syndicated from Explosm.net original https://explosm.net/comics/dating-profile-2
New Cyanide and Happiness Comic
Post Syndicated from Jirka Fajfr original https://aws.amazon.com/blogs/security/how-to-use-the-new-aws-secrets-manager-cost-allocation-tags-feature/
AWS Secrets Manager is a service that you can use to manage, retrieve, and rotate database credentials, application credentials, API keys, and other secrets throughout their lifecycles. You can use Secrets Manager to replace hard-coded credentials in application source code with a runtime call to the Secrets Manager service to retrieve credentials dynamically when you need them. Storing the credentials in Secrets Manager helps avoid unintended access by anyone who inspects your application’s source code, configuration, or components.
Until today, your AWS bill would reflect the total cost of Secrets Manager in any given account, and you had no option to break out the cost per secret to a given cost center or organization.
In this post, we introduce a new feature—Secrets Manager Costs Allocation Tags—and walk through how you can use them for improved visibility into your Secrets Manager costs. Before getting into the details of this new feature, we want to give you primer about cost allocation tags.
A tag is a key-value pair that you assign to an AWS resource. In AWS Cost Explorer, you can activate tags as cost allocation tags. With tags activated, you can categorize and track costs by cost allocation tags. For example, you can create a tag named Group with value Engineering and assign it to resources owned by the engineering team of your company. After activating the Group tag as a cost allocation tag, you can track charges with this tag, filter or group by tags in Cost Explorer, and add tags to reports such as cost and usage reports for further analysis and visualization.
Cost allocation in AWS is a four step process:
After you create and attach the tags to resources, they appear in the AWS Billing console Cost Allocation Tags section under User-defined cost allocation tags within 24 hours. You must activate these tags for AWS to start tracking them for your resources and for the tags to show up in Cost Explorer. When the tags appear under Tags in the Filter or Group by fields in Cost Explorer, you can start filtering or grouping by tag to view usage and charges by tag.
Secrets Manager now supports cost allocation tags, giving you more granular control and visibility into your Secrets Manager costs. You can use this feature to categorize and track your Secrets Manager usage charges at a more detailed level, helping you to better understand and manage your AWS spending and assign costs per secret back to cost centers or organizations.
With this new capability, you can:
To walk through the examples in this post, you need to have the following:
In this example, we assume that you want to manage the cost of your secrets by different cost centers in your organization. Here, we create a tag with CostCenter as a key and the value equal to the cost center codes of the teams that are using secrets.
You’ll walk through two examples, the first one with a cost center for Engineering and a second one with a cost center for Finance. You will reuse those examples throughout this post.
In this example, start by creating and assigning a tag called cost allocation center with the key name: CostCenter and assign a cost center value of 7263 for the engineering department to an existing or new secret.
To assign a user-defined tag to a new or existing secret:

Figure 1: Assign a user-defined tag to an existing secret
7263 for the engineering department and 1121 for the finance department to a second secret.Optionally, you can use the AWS CLI to create the same tags as in the preceding example.
To use the AWS CLI to create tags:
This command produces no output in case of a successful execution.
1121 for the second secret.The next step is to activate the user-defined tags within the AWS Billing and Cost Management console so they can be used.
To activate cost allocation tags:
Note: After you create and apply user-defined tags to your resources, it can take up to 24 hours for the tag keys to appear on your cost allocation tags page for activation. It can then take up to 24 hours for tag keys to activate.

Figure 2: Activate cost allocation tags
You can also activate user-defined tags within the AWS Billing and Cost Management Console using the AWS CLI.
To activate tags using the AWS CLI:
The last step is to view the results for secrets in Cost Explorer. When the tag CostCenter shows up under Tags in the Filter or Group By fields in Cost Explorer, you can start filtering or grouping by the tag to view usage and charges by tag.
When applying the tag filter for Secrets Manager, Cost Explorer displays charges only for resources tagged with the selected tag values. And when grouped by a particular tag, the charges are grouped by each value of the selected tag.
To view results:
As an example, use the following parameters to view results.

Figure 3: Configure report parameters
You can use the resulting report to clearly identify the cost and usage of the two secrets, broken down into the two cost centers: engineering 7263 and finance 1121. Now, you can cross-charge secrets to the corresponding cost centers in your organization and provide a report similar to Figure 4.

Figure 4: Cost and usage report
In this post, we introduced the AWS Secrets Manager Cost Allocation Tags feature and showed you how to use AWS Cost Explorer Costs and Usage Reports to gain secrets usage insights. You can now allocate the cost for every secret to one or more cost centers and charge them accordingly. See the AWS Secrets Manager Cost Allocation Tag documentation to learn more about how you can use Secrets Manager Cost Allocation Tags in your accounts.
Go to the AWS Secrets Manager console to get started. For more information, see AWS Secrets Manager.
To learn more about how to build an effective tagging strategy for cost allocation and financial management, see the Tags for cost allocation and financial management whitepaper.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Post Syndicated from Margaret Jonson original https://aws.amazon.com/blogs/security/reinforce-2025-genai-sessions/

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.
From proof of concepts to large scale production deployments, the rapid advancement of generative AI has ushered in unique opportunities for innovation, but it also introduces a new set of security challenges (and opportunities) that organizations must address. How do you protect retrieval-augmented generation (RAG) or training data while maintaining model effectiveness? What controls are needed for large language model (LLM) interactions? How can I take full advantage of AI agents and model context protocol (MCP) while minimizing risk? At AWS re:Inforce 2025, we’re bringing together security experts, practitioners, and industry leaders to answer these questions with real-world, prescriptive guidance and more.
This year, our generative AI security sessions have been specifically curated and designed to help you build and maintain secure, production AI systems at scale. Whether you’re just beginning your AI security journey or leading mature, enterprise-wide AI initiatives, you’ll find deep practical guidance, hands-on experience, and strategic insights to advance your organization’s security posture.
From foundational concepts to advanced defensive techniques, these sessions encompass critical areas including data protection, model security, identity management, and AI agent resilience. You’ll learn directly from AWS security experts, customers who have successfully implemented secure AI systems, and industry leading partners who are setting new standards in AI safety and security.
In this blog, we highlight some “can’t miss” sessions that cover how to secure AI, but also how security practitioners can leverage AI to help with their critical security missions as well! Join in on the fun, and register for re:Inforce 2025!
Engage with top AWS executives in our Innovation Talks series, where you’ll gain invaluable insights into the forefront of cloud technology. Explore the latest advancements in generative AI, discover robust cloud security strategies, and uncover pioneering architectural concepts that are revolutionizing application development and expanding the possibilities of the AWS Cloud.
SEC301 | Innovation Talk | From possibility to production: A strong, flexible foundation for AI security
Speakers: Hart Rossman (AWS) & Becky Weiss (AWS)
Discover how AWS removes the heavy lifting of AI security, enabling you to accelerate from development to production. This session reveals how the proven AWS security foundation, combined with flexible controls and automated reasoning, helps organizations confidently deploy AI innovations. Through real-world examples, learn how to transform security from a potential roadblock into an innovation enabler. Leave with practical guidance for securing AI workloads today and strategic insights into addressing emerging security challenges, including data security and agentic AI. Learn how the AWS approach to AI security helps you start ahead while maintaining strong security controls.
Breakout sessions are lecture-style, one-hour sessions delivered by AWS experts, customers, and partners—perfect for deepening your knowledge on important topics, gaining actionable insights, and connecting with industry leaders.
Chalk talks are one-hour long, highly interactive sessions with a small audience. This format is ideal for diving deep into specific topics, engaging directly with AWS experts, and getting your questions answered in real time.
Lightning talks are short (20 minute) theater presentations dedicated to a specific customer story, service demo, or AWS Partner offering.
SEC303 | Breakout session | Behind the shields: AWS and Anthropic’s approach to secure AI
Speakers: Matt Saner (AWS) & Shahzeb Jiwani (Anthropic)
Enterprise AI adoption demands robust security. In this session, Join Anthropic’s head of risk governance along with AWS security leaders to reveal how AWS and Anthropic collaborate to deliver enterprise-grade security for LLMs and the generative AI workloads they enable. Learn about the multi-layered security approach spanning infrastructure, data, and models. We’ll explore real-world security architectures, governance frameworks, and risk mitigation strategies. You will leave with a deeper understanding of how to leverage AWS and Anthropic’s security capabilities to accelerate your organization’s AI initiatives while maintaining stringent security and compliance requirements.
SEC304 | Breakout session | Amazon.com testing frameworks and tools for GenAI security and privacy
Speakers: Alex Torres (AWS), Josh Haycraft (Amazon), & Jess Clark (Amazon)
GenAI solutions are launching in a unique, rapidly-shifting security landscape: they may be trained on customer data, they may integrate with internal services or datastores, and they will provide generated content to customers or to other systems. Learn how Amazon.com creates toolkits, systems and frameworks to leverage Large Language Models and Generative AI to enrich customer interactions to promote agility and innovation.
TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Speakers: Himanshu Verma (AWS) & Ryan Holland (AWS)
Discover how the latest AWS detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response – all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.
SEC431 | Chalk talk | Dive deep into data protection architectures for Amazon Bedrock Agents
Speakers: Andrew Kane (AWS) & Gabrielle Dompreh (AWS)
Join this chalk talk to understand how Amazon Bedrock protects your data across Agents and related features, such as Knowledge Bases and Guardrails. Learn about security considerations for cross-region deployments, multi-agent collaboration, and prompt caching. Gain deep insights into architecting secure generative AI solutions that maintain data protection, and discover architectural patterns that keep your applications safe and secure.
APS231 | Chalk talk | Using AWS services to mitigate the OWASP Top 10 for LLM threats
Speakers: Mark Keating (AWS) & Cameron Smith (AWS)
You’ve identified your generative AI use case, tested it and are creating a secure application architecture design. How do you know what generative AI specific threats you should be protecting against, and what tools or services are available that can help? You may have heard of the OWASP Top 10 for LLM Applications, but where or how do you start? Join us as we discuss the OWASP Top 10 threats, the differences between versions, and how AWS can help you mitigate these threats.
DAP332 | Chalk talk | Executive perspective: Risk management for generative AI workloads
Speakers: Jason Garman (AWS) & Mark Ryland (AWS)
Don’t let the perceived complexity of responsible AI keep you from deploying generative AI applications on AWS. In this chalk talk, we will present a framework for breaking down AI safety and security risks, introduce AWS best practices for keeping enterprise data secure in generative AI applications using zero trust principles, and mitigate safety risks using technologies such as Bedrock Guardrails. Discover as a group with fellow security leaders how to identify safety and security risks relevant to your workload, implement appropriate mitigation strategies, and measure efficacy over time.
GRC337 | Chalk talk | Build compliant AI: Implementing controls for emerging regulations
Speakers: Samuel Waymouth (AWS) & Mark Keating (AWS)
As AI adoption accelerates, organizations face increasing regulatory scrutiny and compliance requirements. In this session, learn about the evolving global regulatory landscape for AI, data privacy, and data sovereignty, then see how you can map regulatory requirements and security controls to AWS services and features. We will demonstrate how generative AI can work as a tool for assessment, risk classification and generating compliance guidance. We also show you how to use the latest threat modelling resources developed by AWS. Security professionals and AI practitioners will learn actionable strategies for building AI systems aligned with compliance standards while also maintaining innovation velocity.
SEC221 | Lightning talk | Raising the tide: How AWS is shaping the future of secure AI
Speakers: Matt Saner (AWS)
AI security is a top priority for AWS. By building AI solutions that are secure by design, AWS helps customers innovate quickly with confidence while mitigating emerging threats. But securing AI goes beyond individual organizations—it requires industry-wide standards and best practices. AWS actively contributes to global AI security efforts, including its participation industry standards bodies such as CoSAI (The Coalition for Secure AI), to make sure AI technologies are safe, resilient, and trustworthy. This session will explore how AWS is leading AI security innovation, protecting customers, and collaborating to help shape the future of AI security for the entire industry.
SEC322 | Lightning talk | Managing digital identity in the age of generative AI
Speakers: Arthur Mnev (AWS) & Lily Ashidam (AWS)
In this session, we will explore the challenges and solutions for managing identities in generative AI workloads. This session covers securing API access for LLMs, implementing proper authentication for, in, and with AI services, and maintaining data lineage. Learn practical approaches towards securing generative AI applications while maintaining compliance and governance requirements.
SEC323 | Lightning talk | A practical guide to generative AI agent resilience
Speakers: Yiwen Zhang (AWS) & Jennifer Moran (AWS)
As generative AI agents dominate headlines and technological discussions, enterprise adoption remains in its infancy. GenAI agent resilience is a crucial factor in successful implementation and building user trust. While traditional workload resilience practices—such as database availability, workload capacity, observability, and disaster recovery—remain relevant, GenAI agents present unique challenges. This session delves into the critical dimensions of GenAI agent resilience, including LLM model adaptability, latency management, tool availability, observability, and financial sustainability. We will share practical strategies for building robust, reliable GenAI agents that enterprises can trust and maintain.
SEC326 | Lightning Talk | Secure remote MCP server deployment for Gen AI on AWS
Speakers: Aaron Brown (AWS) & James Ferguson (AWS)
Discover how to securely build and deploy remote Model Context Protocol (MCP) servers on AWS that implement the protocol’s security and trust principles. This session demonstrates OAuth 2.1 authorization patterns that enforce user consent, data privacy, and tool safety requirements. Learn to implement robust security controls using Amazon Cognito, API Gateway, and Lambda while maintaining protocol compliance. Explore practical examples of authorization flows, access controls, and security monitoring that align with MCP specifications.
TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Speakers: Marshall Jones (AWS) & Himanshu Verma (AWS)
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.
Interact with small groups led by an AWS expert providing interactive learning about how to build on AWS. Each builders’ session begins with a short explanation or demonstration of what attendees are building—then it’s your turn to build! The expert will guide you end-to-end through this hands-on experience. Or join Code Talks, our code-focused interactive sessions where AWS experts lead a discussion featuring live coding or code samples as they illuminate the “why” behind AWS solutions. Attendees are encouraged to ask questions and follow along.
Workshops are two-hour interactive sessions where you collaborate in teams or work individually to solve real-world challenges by using AWS services, making them perfect for hands-on learning. Each workshop begins with a brief lecture, followed by dedicated time to work through the problem.
Note: Don’t forget to bring your laptop to build alongside AWS experts.
SEC351 | Builders’ session | Accelerating incident response, compliance & auditing using generative AI
Speakers: Snehal Nahar (AWS), Ravindra Kori (AWS), Rayette Toles-Abdullah (AWS), & Abhijit Barde (AWS)
In this session, we will learn how to use AWS native generative AI capabilities to reduce time to recovery after an incident using enterprise communication tools such as Slack. We will also learn how to use detective controls to identify events that may result in an incident, and also how to use preventive controls to mitigate the risk of an incident occurring. We will use services like Amazon Q Developer, AWS Config, AWS CloudTrail Lake, Amazon CloudWatch and other observability features.
SEC352 | Builders’ session | Agentic AI for security: Building intelligent egress traffic controls
Speakers: Ranjith Rayaprolu (AWS), Anil Nadiminti (AWS), Michael Leighty (AWS), & Dwaragha Sivalingam (AWS)
Learn to build AI-powered security agents that protect your cloud infrastructure. This hands-on session shows you how to use Amazon Bedrock and Bedrock Agents to create intelligent systems that watch over your network. You’ll build Generative AI agents that monitor egress traffic, spot potential threats, and automatically update network firewall to block malicious traffic. Walk away with the skills to implement AI-powered security agents that can reason, decide, and act to protect your cloud infrastructure.
SEC353 | Builders’ session | Threat modeling for generative AI applications
Speakers: Laura Verghote (AWS), Isabelle Mos (AWS), Samuel Waymouth (AWS), & Omar Zoma (AWS)
In this builders’ session, you will learn how to systematically identify and analyze security threats specific to generative AI applications. As organizations rapidly adopt large language models and other generative AI capabilities, understanding the unique security challenges – from prompt injection to data poisoning – becomes critical. You will be guided through the process of creating threat models for common generative AI architectures, with a particular focus on applications built using AWS services like Amazon Bedrock.
SEC451 | Builders’ session | From logs to defense: Generative AI for security automation
Speakers: Ravindra Kori (AWS), Siavash Iran (AWS), Lily Ashidam (AWS), & Yiwen Zhang (AWS)
In this technical session, we’ll demonstrate how to transform traditional operating system log analysis into an intelligent, automated defense system using AWS native services and generative AI. We’ll explore how to build a comprehensive solution that captures security-relevant logs from Windows and Linux systems.
APS351 | Builders’ session | Securing generative AI agents using AWS Well-Architected Framework
Speakers: Krupanidhi Jay (AWS), Ryan Dsouza (AWS), Birender Pal (AWS), & Omkar Mukadam (AWS)
Learn hands-on how to build secure generative AI agent solutions following the AWS Well-Architected Framework’s Generative AI Lens security best practices. Work through practical implementations of endpoint security, prompt engineering guardrails, monitoring systems, and protection against excessive agency while building a production-ready generative AI agent. Through hands-on exercises, build a secure generative AI agent solution incorporating these controls on AWS, involving Amazon Bedrock, Amazon CloudWatch, AWS Identity and Access Management (IAM), and more. You must bring your laptop to participate.
APS353 | Builders’ session | Red teaming your LLM security at scale
Speakers: Otto Kruse (AWS), Owen Hawkins (AWS), Aaron Brown (AWS), & Jeff Lombardo (AWS)
Step into the shoes of an AI-powered red team adversary in the GenAI Red Team Challenge. In this intensive workshop, you’ll deploy an AI security agent to orchestrate sophisticated threat chains against GenAI applications, systematically discovering and exploiting vulnerabilities from prompt injection to boundary testing while mastering automated security testing workflows. In addition, you’ll learn to apply countermeasures, from prompt templating to guardrails. This hands-on, gamified experience helps you think like a threat actor and equips you with practical skills in automated vulnerability testing and risk mitigation against common MITRE and OWASP vulnerabilities for LLM-based applications. You must bring your laptop to participate.
GRC354 | Builders’ session | Best practices for using generative AI to manage cloud compliance
Speakers: Adnan Bilwani (AWS), Ali Maaz (AWS), Artur Rodrigues (AWS), & Peter Pereira (AWS)
Learn how to leverage Amazon Q Developer to streamline cloud compliance management using AWS Config. This hands-on builders’ session demonstrates how to create intelligent compliance checks, automate remediation workflows, and generate detailed compliance reports using generative AI capabilities. Through practical exercises, learn to implement automated compliance monitoring that combines the power of generative AI with AWS Config’s robust compliance framework. You must bring your laptop to participate.
IAM451 | Builders’ session | Securing GenAI apps: Fine-grained access control for Bedrock Agents
Speakers: Edward Sun (AWS), Pravin Nair (AWS), Dustin Ellis (AWS), & Kevin Hakanson (AWS)
Want to secure generative AI applications accessing your organizational data? Learn how to implement intelligent access controls for Amazon Bedrock-powered applications accessing your organizational data. In this builders’ session, you’ll build a defense-in-depth approach that combines authentication using Amazon Cognito and fine-grained authorization with Amazon Verified Permissions to secure access for Bedrock AI agents. Implement layered permissions that protect sensitive data without limiting your GenAI capabilities. You must bring your laptop to participate.
TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Speakers: Scott Taggart (AWS), Joe Wagner (AWS), Laura Verghote (AWS), & Riggs Goodman III (AWS)
Discover how to build your first AI-powered security assistant using Amazon Q Business – no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application. You must bring your laptop to participate.
IAM441 | Code talk | The right way to secure AI agents with code examples
Speakers: Jeff Lombardo (AWS) & Fei Yuan (AWS)
Generative AI agents run tasks on behalf of human users and often interact with each other across on-premises environments and different cloud providers. This brings new challenges in identity authentication, propagation, delegation, and resource authorization in the overall agentic AI solution. Learn how Amazon Cognito’s OAuth2-based identity management, machine-to-machine authentication, combined with Amazon Verified Permissions fine-grained authorization can enable secure delegation patterns for AI agents, while preserving human identity and consent, agent machine identity, and other request context throughout the agent chain. We will walk through real-world examples with agents built on Amazon Bedrock or other frameworks.
TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Amazon Security Lake
Speakers: Chris Lamont-Smith (AWS) & Pratima Singh (AWS)
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.
SEC371 | Workshop | Red Team approaches to practical generative AI defenses
Speakers: Mac Stevens (AWS) & Cameron Smith (AWS)
This workshop takes a hands-on approach to Generative AI security, focusing on Amazon Bedrock, Amazon SageMaker, and related services. We’ll begin by examining Bedrock’s core security principles, including data protection during inference and in features like Agents, Guardrails, and Knowledge Bases. Participants will gain insights into the internal architectures and security implications of context windows, system prompts, agent orchestration, and more. The session then transitions into hands-on red teaming exercises using SageMaker. We’ll subsequently explore defensive strategies against these threat vectors and discuss methods for integrating these practices into development workflows. Participants will leave equipped with a holistic understanding of Generative AI security, from individual model protection to safeguarding complex, multi-component systems.
APS371 | Workshop | Securing your generative AI applications on AWS
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
In this workshop, discover how to secure generative AI applications using AWS services and features. Explore how to deploy a vulnerable sample generative AI application and then layer security controls to protect, detect, and respond to security issues. Learn how to apply similar controls to the generative AI applications in your organization. You must bring your laptop to participate.
DAP371 | Workshop | Defend your AI: Mitigate prompt injection with Amazon Bedrock
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
Master the art of identifying and mitigating prompt injection vulnerabilities in generative AI systems through this hands-on workshop. Using Amazon Bedrock, participants will explore both offensive and defensive prompt engineering techniques to understand the security implications of large language models in production environments. In this session you will understand how prompt injection attacks work, complete an interactive ‘capture the flag’ style challenge attempting to exploit a simulated AI environment, and learn to implement defensive controls using Amazon Bedrock Guardrails. You must bring your laptop to participate.
Don’t miss this opportunity to learn from industry experts and AWS leaders about securing your AI implementations. Register for AWS re:Inforce 2025 today to reserve your spot in these sessions. Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus partner sessions and code talks.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from daroc original https://lwn.net/Articles/1021825/
Srinivas Narayana led a remote session about extending
Agni to prove the correctness of
the BPF verifier’s handling of different execution paths as part of the Linux Storage,
Filesystem, Memory Management, and BPF Summit. The problem of ensuring the
correctness of path exploration
is much more difficult than the problem of
ensuring the correctness of arithmetic operations
(which was
the subject of the previous session), however. Narayana’s plan to
tackle the problem makes use of a mixture of specialized techniques — and may
need some assistance from the BPF developers to make it feasible at all.
Post Syndicated from Brianna Rosentrater original https://aws.amazon.com/blogs/compute/control-instance-placement-using-asset-level-capacity-management-for-aws-outposts/
AWS Outposts supports self-service capacity management at the entire Outpost level, or at the individual asset level, making it easy for you to view and manage compute capacity on your Outposts. This feature supports both Outposts rack (such as the recently announced second-generation Outposts rack) and Outposts server. A default capacity configuration for each new Outpost is determined during the ordering process. This default configuration can subsequently be modified to create a range of Amazon Elastic Compute Cloud (Amazon EC2) instance sizes and quantities to meet your changing business needs. For more information on performing Outposts level multi-asset reconfigurations, go to Dynamically reconfigure your AWS Outposts capacity using Capacity Tasks.
The release of Asset Level Capacity Management allows you to control the configuration of specific assets within your Outpost, which can be useful when planning strategies for EC2 Auto Scaling groups and host-level high availability. An Outpost asset can be a single server within an Outposts rack, or an Outposts server. This post focuses on how to use Asset Level Capacity Management to perform single-host reconfigurations, and how this can be used with Amazon EC2 placement groups to control instance placement on your Outpost.
When you place an Outposts order, you determine the capacity configuration of each Outpost based on the anticipated workload requirements. You can scale your Outposts up or out as needed during your commitment term. For further details on Outpost capacity planning including best practices, refer to the Capacity Planning – AWS Outposts High Availability Design and Architecture whitepaper. We recommend planning spare capacity for N+M host availability per instance family when making modifications to your Outpost capacity configuration for workloads that need to be highly available. To calculate, take the number of assets (N) you need to run all your workloads, and then add (M) additional assets to meet your requirements for server availability during failure and maintenance events.
You also need to plan for instance level high availability when deciding to reconfigure particular assets. For example, say you have two C5 assets, and each one is configured homogeneously to provide C5.2xlarge instances. If you have an Auto Scaling group that specifies C5.2xlarge in its launch template, and you perform an asset level reconfiguration of one of your C5 assets so that it only offers C5.4xlarge instances, then your Auto Scaling group can only launch instances on the one C5 host configured to provide C5.2xlarge instances. If that host fails, then the Auto Scaling group is unable to launch new C5.2xlarge instances on the other host unless the Auto Scaling group launch template is modified. Understanding failure scenario behavior and how much capacity you want to reserve for high availability is key to capacity management and disaster recovery planning. For highly available workloads, we recommend spreading your instances across as many assets as possible.
Outposts rack supports EC2 placement groups, and two placement group options are available only on Outposts: rack level spread, and host level spread. This allows you to spread out instances across underlying hardware on an Outpost at your site. To use a rack level spread placement group, you must have two or more physical Outpost racks. Each spread strategy can be used to create resilient Outposts architectures that can withstand a rack or host failure depending on the respective strategy used.

Figure 1: Outposts rack showing a rack level spread EC2 placement group
Using a multi-rack Outpost, you can spread your EC2 instances across multiple racks with a rack level spread EC2 placement group. When used with Auto Scaling groups, this allows you to withstand an individual rack or multi-asset failure. When your Auto Scaling group detects you’ve lost instances on one of your racks, it automatically relaunches the instances using the assets on your other racks if you have available capacity. To use this strategy to increase your workload resiliency, each rack would need to have assets that can support the instance type (C5 is used in the preceding figure) and size used in your Auto Scaling group launch template. The expanded functionality that asset level capacity management brings to capacity tasks allows you to configure your Outpost so that each rack has at least one asset that can support the instances used in your Auto Scaling groups. Configure your assets on each rack to meet your resiliency goals for host failure tolerance as well. This configuration can be done in an on-demand, self-service fashion to meet the needs of your evolving workloads if instance requirements change over time.

Figure 2: Outposts rack showing a host level spread EC2 placement group
Although rack level spread EC2 placement groups need a multi-rack Outpost, host level spread EC2 placement groups can be used within a single rack Outpost to provide resiliency for your workloads at the asset level. When used with Auto Scaling groups, this allows you to withstand an individual asset or multi-asset failure depending on your Outpost configuration. When your Auto Scaling group detects you’ve lost instances on one of your assets due to a hardware failure, it automatically relaunches the instances using your other assets on your Outpost if you have available capacity. To use this strategy to increase your workload resiliency, you would need to have at least two assets within your Outposts rack that can support the instance type (R5 and M5 are used in the preceding figure) and size used in your Auto Scaling group launch template. Outposts also supports using attribute-based instance type selection if multiple instance types meet your workload needs based on some minimum resource requirements. With the expanded functionality that asset level capacity management brings to capacity tasks, you can configure your Outposts rack so that each asset type can support the instance size used in your Auto Scaling groups. This configuration can be done in an on-demand, self-service fashion to meet the needs of your evolving workloads if instance requirements change over time.
Asset Level Capacity Management allows you to target a specific Outpost asset to change its capacity configuration directly, allowing granular control over instance capacity pool configurations. Outpost assets are referred to by a unique ten-digit Asset ID. The first step in this process is identifying a suitable asset on which to perform the capacity task. To do this, you can use the rack view within the Outposts console page to view each asset, its current capacity configuration, and its current usage. Choosing an asset with fewer running instances may increase the chances of the capacity task being successful without needing instances to be stopped.
In the following example, the rack view has been filtered by the R5 family resulting in the two R5 assets being displayed. The Show instance details option has also been chosen to show the instance IDs of the running instances on our Outposts rack.

Figure 3: Rack view of the Outposts console
When you have identified the asset to target for the capacity task, you can either choose the Modify option in the top right of the asset itself or go to Capacity Tasks from the console menu and choose the asset ID directly from the dropdown menu.

Figure 4: Capacity tasks console experience
From here, you have the option to use the capacity configuration builder to interactively modify your Outposts capacity layout, or you can upload a capacity configuration plan JSON document with the necessary configuration. When building the capacity task, you have two options to choose from when handling instances that are blocking the task from executing. The default option is set to fail the capacity task if this occurs. However, this can be set to wait for the instances to be stopped so that the task can continue. If this option is chosen, then the asset is placed into an isolated state until either the capacity task completes or is cancelled, thus preventing any further instances launches on the impacted asset.
If there are instances on the asset that can’t be stopped to complete the capacity task, then they can be chosen from the Instances to keep as-is section. Only the instances running on the impacted asset are listed. If a capacity task can’t be completed while leaving the chosen instances running, the capacity task fails.
In the following example, the capacity configuration requested for the asset results in the removal of one r5.4xlarge and two r5.2xlarge instances, which creates sufficient space for the creation of 12 r5.large instances. This asset also has three instances running on it which have all been chosen to keep as-is during the execution of the task.

Figure 5: Capacity task example showing r5 asset level capacity management
You can also execute capacity tasks programmatically If you prefer through CLI or API calls. For example, using the start-capacity-task CLI to submit the same configuration would look as follows:
After defining the capacity task, you are presented with an overview of the requested changes before submitting the task for execution. When it’s submitted, the task first enters a Requested status while the configuration is evaluated, before either being moved to In Progress if the task is valid or Failed if it’s invalid or blocked by running instances.
When the capacity task has successfully completed and the capacity pools for the asset are updated, you can validate this by returning to the rack view within the Outpost console, or by using the CLI/API. The following is an example using the list-assets CLI command:
Only a single capacity task for an asset can be executing at any given time. If you attempt to create a second capacity task for the same asset while the original is still in a Requesting or In Progress status, then the submission of the task fails. However, you can submit multiple capacity tasks for unique assets within the same Outpost. For example, using the CLI commands, you could execute a single script to change the capacity configuration of all assets within an Outpost through individual asset level capacity tasks.
This post demonstrates how to use Asset Level Capacity Management with your AWS Outposts, and reviews considerations for maintaining a highly available capacity configuration. For more information on how to manage and monitor your capacity configuration on Outposts, see the Capacity management for AWS Outposts user guide and the Capacity planning section of the Outposts High Availability Design and Architecture Considerations whitepaper. Reach out to your AWS account team, or fill out this form to learn more about Outposts and self-service capacity management.
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-aurora-dsql-is-now-generally-available/
Today, we’re announcing the general availability of Amazon Aurora DSQL, the fastest serverless distributed SQL database with virtually unlimited scale, the highest availability, and zero infrastructure management for always available applications. You can remove the operational burden of patching, upgrades, and maintenance downtime and count on an easy-to-use developer experience to create a new database in a few quick steps.
 When we introduced the preview of Aurora DSQL at AWS re:Invent 2024, our customers were excited by this innovative solution to simplify complex relational database challenges. In his keynote, Dr. Werner Vogels, CTO of Amazon.com, talked about managing complexity upfront in the design of Aurora DSQL. Unlike most traditional databases, Aurora DSQL is disaggregated into multiple independent components such as a query processor, adjudicator, journal, and crossbar.
These components have high cohesion, communicate through well-specified APIs, and scale independently based on your workloads. This architecture enables multi-Region strong consistency with low latency and globally synchronized time. To learn more about how Aurora DSQL works behind the scenes, watch Dr. Werner Vogels’ keynote and read about an Aurora DSQL story.
The architecture of Amazon Aurora DSQL
Your application can use the fastest distributed SQL reads and writes and scale to meet any workload demand without any database sharding or instance upgrades. With Aurora DSQL, its active-active distributed architecture is designed for 99.99 percent availability in a single Region and 99.999 percent availability across multiple Regions. This means your applications can continue to read and write with strong consistency, even in the rare case an application is unable to connect to a Region cluster endpoint.

In a single-Region configuration, Aurora DSQL commits all write transactions to a distributed transaction log and synchronously replicates all committed log data to user storage replicas in three Availability Zones. Cluster storage replicas are distributed across a storage fleet and automatically scale to ensure optimal read performance.
Multi-Region clusters provide the same resilience and connectivity as single-Region clusters while improving availability through two Regional endpoints, one for each peered cluster Region. Both endpoints of a peered cluster present a single logical database and support concurrent read and write operations with strong data consistency. A third Region acts as a log-only witness which means there is is no cluster resource or endpoint. This means you can balance applications and connections for geographic locations, performance, or resiliency purposes, making sure readers consistently see the same data.
Aurora DSQL is an ideal choice to support applications using microservices and event-driven architectures, and you can design highly scalable solutions for industries such as banking, ecommerce, travel, and retail. It’s also ideal for multi-tenant software as a service (SaaS) applications and data-driven services like payment processing, gaming platforms, and social media applications that require multi-Region scalability and resilience.
Getting started with Amazon Aurora DSQL
Aurora DSQL provides a easy-to-use experience, starting with a simple console experience. You can use familiar SQL clients to leverage existing skillsets, and integration with other AWS services to improve managing databases.
To create an Aurora DSQL cluster, go to the Aurora DSQL console and choose Create cluster. You can choose either Single-Region or Multi-Region configuration options to help you establish the right database infrastructure for your needs.

1. Create a single-Region cluster
To create a single-Region cluster, you only choose Create cluster. That’s all.

In a few minutes, you’ll see your Aurora DSQL cluster created. To connect your cluster, you can use your favorite SQL client such as PostgreSQL interactive terminal, DBeaver, JetBrains DataGrip, or you can take various programmable approaches with a database endpoint and authentication token as a password. You can integrate with AWS Secrets Manager for automated token generation and rotation to secure and simplify managing credentials across your infrastructure.

To get the authentication token, choose Connect and Get Token in your cluster detail page. Copy the endpoint from Endpoint (Host) and the generated authentication token after Connect as admin is chosen in the Authentication token (Password) section.
Then, choose Open in CloudShell, and with a few clicks, you can seamlessly connect to your cluster.

After you connect the Aurora DSQL cluster, test your cluster by running sample SQL statements. You can also query SQL statements for your applications using your favorite programming languages: Python, Java, JavaScript, C++, Ruby, .NET, Rust, and Golang. You can build sample applications using a Django, Ruby on Rails, and AWS Lambda application to interact with Amazon Aurora DSQL.
2. Create a multi-Region cluster
To create a multi-Region cluster, you need to add the other cluster’s Amazon Resource Name (ARN) to peer the clusters.
To create the first cluster, choose Multi-Region in the console. You will also be required to choose the Witness Region, which receives data written to any peered Region but doesn’t have an endpoint. Choose Create cluster. If you already have a remote Region cluster, you can optionally enter its ARN.

Next, add an existing remote cluster or create your second cluster in another Region by choosing Create cluster.

Now, you can create the second cluster with your peer cluster ARN as the first cluster.

When the second cluster is created, you must peer the cluster in us-east-1 in order to complete the multi-Region creation.

Go to the first cluster page and choose Peer to confirm cluster peering for both clusters.

Now, your multi-Region cluster is created successfully. You can see details about the peers that are in other Regions in the Peers tab.

To get hands-on experience with Aurora DSQL, you can use this step-by-step workshop. It walks through the architecture, key considerations, and best practices as you build a sample retail rewards point application with active-active resiliency.
You can use the AWS SDKs, AWS Comand Line Interface (AWS CLI), and Aurora DSQL APIs to create and manage Aurora DSQL programmatically. To learn more, visit Setting up Aurora DSQL clusters in the Amazon Aurora DSQL User Guide.
What did we add after the preview?
We used your feedback and suggestions during the preview period to add new capabilities. We’ve highlighted a few of the new features and capabilities:
Aurora DSQL now provides a Model Context Protocol (MCP) server to improve developer productivity by making it easy for your generative AI models and database to interact through natural language. For example, install Amazon Q Developer CLI and configure Aurora DSQL MCP server. Amazon Q Developer CLI now has access to an Aurora DSQL cluster. You can easily explore the schema of your database, understand the structure of the tables, and even execute complex SQL queries, all without having to write any additional integration code.
Now available
Amazon Aurora DSQL is available today in the AWS US East (N. Virginia), US East (Ohio), US West (Oregon) Regions for single- and multi-Region clusters (two peers and one witness Region), Asia Pacific (Osaka) and Asia Pacific (Tokyo) for single-Region clusters, and Europe (Ireland), Europe (London), and Europe (Paris) for single-Region clusters.
You’re billed on a monthly basis using a single normalized billing unit called Distributed Processing Unit (DPU) for all request-based activity such as read/write. Storage is based on the total size of your database and measured in GB-months. You are only charged for one logical copy of your data per single-Region cluster or multi-Region peered cluster. As a part of the AWS Free Tier, your first 100,000 DPUs and 1 GB-month of storage each month is free. To learn more, visit Amazon Aurora DSQL Pricing.
Give Aurora DSQL a try for free in the Aurora DSQL console. For more information, visit the Aurora DSQL User Guide and send feedback to AWS re:Post for Aurora DSQL or through your usual AWS support contacts.
— Channy
Post Syndicated from Arthi Jaganathan original https://aws.amazon.com/blogs/architecture/transforming-mayas-api-management-with-amazon-api-gateway/
In this post, you will learn how Amazon Web Services (AWS) customer, Maya, the Philippines’ leading fintech company and digital bank, built an API management platform to address the growing complexities of managing multiple APIs hosted on Amazon API Gateway. API Gateway is a fully managed service that you can use to create RESTful and WebSocket APIs.
At Maya, different teams build APIs to expose their services to merchants. As the number of applications grew, the overhead of managing APIs increased. An API platform is a set of tools to simplify and standardize across API management concerns such as security, governance, automated deployments, observability, and integrations with multiple AWS accounts. This frees up application teams to focus on features while offloading management concerns to the API platform.
Prior to implementing the API platform, Maya used a decentralized API management approach, which created significant challenges. Individual teams operated independent API gateways, resulting in fragmented infrastructure, leading to several issues:
To address these challenges, Maya implemented an API platform, code-named Unified API Gateway. This centralized API management helps enforce consistent standards and improve overall security and observability. The following image illustrates the architecture of the Unified API Gateway and how it integrates with backend services managed and owned by different teams across different AWS accounts.

API Platform Architecture
Maya chose to host all APIs in a central API account to centralize governance. This is managed by a dedicated shared services cloud team. Amazon CloudFront with AWS WAF and AWS Shield Advanced integration provides perimeter security. An AWS Lambda authorizer provides application security by managing authentication, authorization, and session management. This mitigates against the OWASP top 10 API security risks.
Integration to backend services is configured through API Gateway private integration and AWS Transit Gateway. In a decentralized API deployment strategy where APIs are co-hosted with the service in the respective AWS account, the integration will be simpler because you won’t need cross-account network connectivity. You will still benefit from the API management techniques covered in this post.
OpenAPI Specification (OAS) provides a structured definition for APIs. As shown in the following figure, service teams define the API OAS specification. This is embedded in Terraform infrastructure-as-code template for API Gateway. These are checked into source code repository and deployed using GitLab CI.

API Gateway Infrastructure-as-code (IaC) Pipeline
A configuration file used as a Terraform template supplies parameters for components of the solution such as backend integration, Lambda authorizer details, and additional headers for auditing. The following OAS snippets demonstrate this.
x-amazon-apigateway-integration:
   type: "http_proxy"
   connectionId: "${vpc_link_id}"
   httpMethod: "GET"
uri: "http://$${stageVariables.url}:11620/v1/api/endpoint/{id}" # double $ is not a typox-amazon-apigateway-integration:
type: "http_proxy"
connectionId: "${vpc_link_id}"
httpMethod: "GET"
uri: "http://$${stageVariables.url}:11620/v1/api/endpoint/{id}"
requestParameters:
integration.request.header.x-requesting-service-id: "'api-gw'"
integration.request.header.x-org-customer-id: "context.authorizer.x-org-customer-id"securitySchemes:
lambda-authorizer:
type: "${authorizer_type}"
name: "${authorizer_name}"
x-amazon-apigateway-authtype: "custom"
x-amazon-apigateway-authorizer:
type: "request"
authorizerUri: "${authorizer_uri}"
authorizerCredentials: "${authorizer_credentials}"
identitySource: "${authorizer_identity_source}"API Gateway supports most of the OpenAPI 2.0 specification and the OpenAPI 3.0 specification but there are a few exceptions. Maya uses a custom plugin in the pipeline to enforce necessary limiting rules to help ensure compatibility with API Gateway.
To simplify deployment for development teams, a custom Terraform module abstracts away the API Gateway implementation details.
module "test-microservice-api-gateway" {
  # module version parameters
  source = "gitlabinstance.com/platform-engineering/apigw-terraform-module/aws"
  version = "1.2.7"

  # module deployed infrastructure parameters
  api_name = var.api_name
  api_mapping_path = var.api_mapping_path
  environment = var.environment
  aws_region = var.aws_region
  account_id = var.account_id
  tags = var.tags
  domain_name = var.domain_name
  stage_name = var.stage_name

  oas_path = var.oas_path # this value is populated via environment variable in Gitlab CI/CD

  providers = {
     aws = aws.apigw
  }
  authorizer_credentials = var.authorizer_credentials
  authorizer_uri = var.authorizer_uri
  vpc_link_id = var.vpc_link_id
  endpoint_url = var.endpoint_url
}
To use multi-level prefixes for custom domains with REST API Gateway, you need the Terraform module for API Gateway v2.
resource "aws_api_gateway_rest_api" "apigw" {
   name = "${var.environment}-${var.api_name}"
   body = templatefile(
     local.oasFilePath,
     {
       vpc_link_id = var.vpc_link_id
       authorizer_uri = var.authorizer_uri
       authorizer_credentials = var.authorizer_credentials
     }
  )
  description = "API Gateway for ${var.api_name}"
  endpoint_configuration {
    types = ["REGIONAL"]
  }

   # Default endpoint needs to be disabled if CloudFront is used as entry point to API Gateway
  disable_execute_api_endpoint = true
  tags = local.tags
  }

  # Use apigatewayv2 in order to have multi level base path ex. /v1/service_name
  resource "aws_apigatewayv2_api_mapping" "this" {
     domain_name = var.domain_name
    api_id = aws_api_gateway_rest_api.apigw.id
    stage = aws_api_gateway_stage.apigw.stage_name
    api_mapping_key = var.api_mapping_path
}Maya’s Unified API Gateway implements a robust, multi-layered security strategy. This approach helps ensure comprehensive protection from external threats and enforces stringent access control policies.
AWS WAF inspects and filters incoming traffic to protect against common web exploits, including OWASP Top 10, such as SQL injection and cross-site scripting attacks. A combination of custom and managed rule sets blocks malicious requests and enforces security policies. AWS Shield Advanced mitigates distributed denial of service (DDoS) attacks and provides 24/7 access to the AWS Shield Response Team (SRT) for expert support during attack events. This helps ensure high availability and resiliency.
API Gateway is integrated with a Lambda authorizer for authentication and authorization. The custom function implements fine-grained access control based on several factors such as identity, roles, and scopes.
To help ensure the consistency and integrity of the API configurations, all updates and deployments are strictly managed through an automated infrastructure-as-code (IaC) pipeline. This helps eliminate the risk of unauthorized or accidental manual changes to the API Gateway and any underlying infrastructure. The IaC pipeline makes sure that all API configurations, including security settings, are deployed through a controlled and auditable process. This prevents configuration drift and makes sure that security policies are consistently applied across all APIs. This also means that all changes are subject to code reviews and version control, adding another layer of security and traceability.
Maya’s Unified API Gateway prioritizes comprehensive observability to proactively monitor API performance, identify potential issues, and provide a seamless user experience. It uses a combination of AWS services and integrated tools to achieve this.
Amazon CloudWatch is used to monitor key performance metrics, including latency, error rates, and requests counts. CloudWatch provides real-time insights into the health and performance of APIs. Alerts on P95 and P99 values help identify and address performance bottlenecks, ensuring responsiveness.
CloudWatch metrics are streamed to Dynatrace, an application performance monitoring (APM) tool. The centralized view helps correlate data from various sources, create custom dashboards, and configure intelligent alerts based on predefined thresholds.
To help ensure complete visibility into API activity, the Lambda authorizer and API Gateway access logs are centralized in Splunk. This provides a comprehensive audit trail to track authentication and authorization events, identify security incidents, and troubleshoot API requests. Headers generated after authentication and authorization are done are passed down to the backend services for proper log correlation.
The Unified API Gateway will continue to evolve to meet the growing needs of the organization and its partners and customers. The following are the key future enhancements that will further streamline API management, improve the developer experience, and enhance security.
This post has described the creation of Maya’s robust API management and governance solution, using a combination of native AWS services and powerful partner tools such as Terraform and Dynatrace. We’ve demonstrated how this Unified API Gateway has streamlined and automated core API processes, transforming Maya’s previously fragmented infrastructure into a secure and observable ecosystem. By establishing clear guardrails, the API solution team empowers developers to rapidly deploy APIs while maintaining consistent standards.
With the recent implementation of this solution across more teams, Maya is focused on defining and tracking key performance indicators (KPIs). We anticipate measuring critical metrics such as API onboarding efficiency, developer experience, API latency, and security incident rates. These insights will serve as a foundation for continuous improvement and optimization, ensuring the solution’s sustained effectiveness and evolution.
Visit the API platform guidance on Serverlessland to learn more about building API platforms. See the API Gateway pattern collection to learn more about designing REST API integrations on AWS.
Post Syndicated from Kalyan Janaki original https://aws.amazon.com/blogs/big-data/unify-streaming-and-analytical-data-with-amazon-data-firehose-and-amazon-sagemaker-lakehouse/
Organizations are increasingly required to derive real-time insights from their data while maintaining the ability to perform analytics. This dual requirement presents a significant challenge: how to effectively bridge the gap between streaming data and analytical workloads without creating complex, hard-to-maintain data pipelines. In this post, we demonstrate how to simplify this process using Amazon Data Firehose (Firehose) to deliver streaming data directly to Apache Iceberg tables in Amazon SageMaker Lakehouse, creating a streamlined pipeline that reduces complexity and maintenance overhead.
Streaming data empowers AI and machine learning (ML) models to learn and adapt in real time, which is crucial for applications that require immediate insights or dynamic responses to changing conditions. This creates new opportunities for business agility and innovation. Key use cases include predicting equipment failures based on sensor data, monitoring supply chain processes in real time, and enabling AI applications to respond dynamically to changing conditions. Real-time streaming data helps customers make quick decisions, fundamentally changing how businesses compete in real-time markets.
Amazon Data Firehose seamlessly acquires, transforms, and delivers data streams to lakehouses, data lakes, data warehouses, and analytics services, with automatic scaling and delivery within seconds. For analytical workloads, a lakehouse architecture has emerged as an effective solution, combining the best elements of data lakes and data warehouses. Apache Iceberg, an open table format, enables this transformation by providing transactional guarantees, schema evolution, and efficient metadata handling that were previously only available in traditional data warehouses. SageMaker Lakehouse unifies your data across Amazon Simple Storage Service (Amazon S3) data lakes, Amazon Redshift data warehouses, and other sources, and gives you the flexibility to access your data in-place with Iceberg-compatible tools and engines. By using SageMaker Lakehouse, organizations can harness the power of Iceberg while benefiting from the scalability and flexibility of a cloud-based solution. This integration removes the traditional barriers between data storage and ML processes, so data workers can work directly with Iceberg tables in their preferred tools and notebooks.
In this post, we show you how to create Iceberg tables in Amazon SageMaker Unified Studio and stream data to these tables using Firehose. With this integration, data engineers, analysts, and data scientists can seamlessly collaborate and build end-to-end analytics and ML workflows using SageMaker Unified Studio, removing traditional silos and accelerating the journey from data ingestion to production ML models.
The following diagram illustrates the architecture of how Firehose can deliver real-time data to SageMaker Lakehouse.

This post includes an AWS CloudFormation template to set up supporting resources so Firehose can deliver streaming data to Iceberg tables. You can review and customize it to suit your needs. The template performs the following operations:
For this walkthrough, you should have the following prerequisites:
streaming_datalake as the AWS Glue database name.After you create the prerequisites, verify you can log in to SageMaker Unified Studio and the project is created successfully. Every project created in SageMaker Unified Studio gets a project location and project IAM role, as highlighted in the following screenshot.

For this solution, we use Amazon Athena as the engine for our query editor. Complete the following steps to create your Iceberg table:


The next step is to deploy the required resources into your AWS environment by using a CloudFormation template. Complete the following steps:

firehose-lakehouse.

Complete the following steps to create a Firehose stream to deliver data to Amazon S3:

This example chooses Direct PUT as the source, but you can apply the same steps for other Firehose sources, such as Amazon Kinesis Data Streams and Amazon Managed Streaming for Apache Kafka (Amazon MSK).

firehose-iceberg-events.

Make sure you enclose the database and table names in double quotes if you want to deliver data to a single database and table. Amazon Data Firehose can also route records to different tables based on the content of the record. For more information, refer to Route incoming records to different Iceberg tables.


s3://firehose-demo-iceberg-<account_id>-<region>) and the error output prefix (error/events-1/).
Firehose-Iceberg-Stack-FirehoseIamRole-*, created by the CloudFormation template.Use the Amazon Kinesis Data Generator to publish data records into your Firehose stream:


You can monitor the progress of the data stream.

Now that Firehose is delivering data to SageMaker Lakehouse, you can perform analytics on that data in SageMaker Unified Studio using different AWS analytics services.

It’s generally a good practice to clean up the resources created as part of this post to avoid additional cost. Complete the following steps:
stack firehose-lakehouse* and on the Actions menu, choose Delete Stack.Streaming data allows models to make predictions or decisions based on the latest information, which is crucial for time-sensitive applications. By incorporating real-time data, models can make more accurate predictions and decisions. Streaming data can help organizations avoid the costs associated with storing and processing large datasets, because it focuses on the most relevant information. Amazon Data Firehose makes it straightforward to bring real-time streaming data to data lakes in Iceberg format and unifying it with other data assets in SageMaker Lakehouse, making streaming data accessible by various analytics and AI services in SageMaker Unified Studio to deliver real-time insights. Try out the solution for your own use case, and share your feedback and questions in the comments.
 Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.
 Phaneendra Vuliyaragoli is a Product Management Lead for Amazon Data Firehose at AWS. In this role, Phaneendra leads the product and go-to-market strategy for Amazon Data Firehose.
 Maria Ho is a Product Marketing Manager for Streaming and Messaging services at AWS. She works with services including Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Managed Service for Apache Flink, Amazon Data Firehose, Amazon Kinesis Data Streams, Amazon MQ, Amazon Simple Queue Service (Amazon SQS), and Amazon Simple Notification Services (Amazon SNS).
Post Syndicated from Nisha Amthul original https://aws.amazon.com/blogs/security/navigating-the-threat-detection-and-incident-response-track-at-reinforce-2025/
A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.
We’re counting down to AWS re:Inforce, our annual cloud security event! We are thrilled to invite security enthusiasts and builders to join us in Philadelphia, PA June 16–18, 2025, for an immersive three-day journey into cloud security learning. At AWS re:Inforce, you’ll have the chance to explore the breadth of the Amazon Web Services (AWS) security landscape, learn how to operationalize security services, and enhance your skills and confidence in cloud security to improve your organization’s security posture. As an attendee, you will have access to over 250 sessions across multiple topic tracks, including data protection; identity and access management; threat detection and incident response; network and infrastructure security; generative AI; governance, risk, and compliance; and application security. Plus, get ready to be inspired by our lineup of customer speakers, who will share their firsthand experiences of innovating securely on AWS.
In this post, we provide an overview of the key sessions that include lecture-style presentations featuring real-world use cases from our customers and interactive small-group sessions led by AWS experts that guide you through practical problems and solutions.
The threat detection and incident response track is designed to demonstrate how to detect and respond to security risks to help protect workloads at scale. AWS experts and customers will present key topics such as unified cloud security, threat detection, vulnerability management, cloud security posture management, integrated detection-to-response, threat intelligence, operationalization of AWS security services, container security, effective security investigation, security analytics, and incident response best practices. We’ll also explore both strengthening security through the use of generative AI and securing generative AI workloads.
TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Discover how AWS’s latest detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response—all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.
TDR302 | Breakout session | Multi-stage threat detection using GuardDuty and MITRE
Enhance your threat detection capabilities by leveraging Amazon GuardDuty Extended Threat Detection alongside MITRE frameworks. In this session, Shane Steiger Esq. from MITRE Corp demonstrates how to effectively identify and respond to multi-stage security events in your AWS environment. Learn practical strategies for implementing detection controls, developing response procedures, and building resilient cloud architectures. Discover how integrating GuardDuty with MITRE frameworks can strengthen your event detection and response strategy.
TDR303 | Breakout session | Building secure generative AI security tools, featuring Trellix
Learn how to build enterprise-grade generative AI security tools that unify security data and enable natural language investigations. This session demonstrates practical approaches for developing secure generative AI solutions, including implementation patterns for data privacy and compliance controls. Explore real-world architectures combining AWS foundation models with security orchestration. Hear how Trellix achieved 23x cost savings while maintaining 95% accuracy using Amazon Bedrock models. Leave with strategies to build secure AI assistants that support your security teams.
TDR304 | Breakout session | Scaling AWS threat intelligence to protect customers
Discover how AWS builds and operates threat intelligence at unprecedented scale to protect millions of customers. In this session, dive deep into two critical security functions: Amazon Threat Intelligence, which tracks and defends against sophisticated threats, and Active Defense, our security data processing architecture that analyzes over 4 billion records per second. Learn how these capabilities work together to power AWS security services and provide automated protection for your applications. See how AWS uses this intelligence to continuously enhance security services that help keep your workloads safe.
TDR305 | Breakout session | Scale Vulnerability Management Using Amazon Inspector
Want to strengthen Lambda security and streamline vulnerability management? Learn how Amazon Inspector uses generative AI to provide in-context code patches and automate SBOM management. Discover practical techniques for CI/CD integration, cross-account scanning, and automated remediation workflows. Explore built-in integrations with Security Hub and EventBridge to enhance security operations across your AWS environment.
TDR306 | Breakout session | Enterprise Security at Scale: SAP’s AWS Blueprint
How does SAP protect thousands of AWS accounts? Learn their blueprint for implementing Amazon GuardDuty protection plans alongside Extended Threat Detection to identify sophisticated threat patterns. Discover their framework for standardizing AWS Security Hub controls and automated remediation workflows at scale. Walk away with practical strategies to enhance enterprise security operations across AWS Organizations.
TDR331 | Chalk talk | Ask AWS: Your ransomware questions answered
Get answers to your most critical ransomware questions in this interactive Q&A session. Learn how AWS security features and best practices can help you detect, respond to, and recover from ransomware threats. Our experts will share practical guidance on identifying early warning signs, implementing effective incident response, and strengthening your overall ransomware resilience. Bring your toughest questions about emerging ransomware tactics and cloud protection strategies. Walk away with actionable insights to help secure your data and operations using AWS security capabilities.
TDR332 | Chalk talk | Decoding AWS CIRT tactics & techniques for proactive defense
Learn directly from AWS Customer Incident Response Team (CIRT) experts who help customers respond to critical security events. Discover real-world insights about emerging threat tactics and techniques observed across AWS environments. We’ll share practical detection and mitigation strategies that align with the Shared Responsibility Model, helping you strengthen your security posture. Walk away with actionable best practices from CIRT’s frontline experience defending against evolving threats, and learn how to apply these insights to protect your AWS workloads.
TDR333 | Chalk talk | Strategy for prioritization and response
Join this session to discuss managing security posture and risk across multiple accounts, regions, and resources. We will explore the decision-making process around how you prioritize security alerts and risk using AWS security services. After prioritization, we will discuss a framework for responding to and remediating security findings. We will talk through the decision-making process of responding to findings, considerations for auto-remediation, and how to facilitate a quick and thorough response to the most critical security findings.
TDR334 | Chalk talk | Strengthen Security: Making GuardDuty Protection Plans Work for You
Discover how to maximize your threat detection capabilities by selecting the right Amazon GuardDuty protection plans for your environment. Learn to evaluate protection features that matter most for your AWS workloads and understand the value each plan brings to your security strategy. Through practical scenarios, explore cost-effective implementation strategies across your AWS accounts. Leave with actionable insights for optimizing your Amazon GuardDuty deployment to enhance protection of your AWS workloads and data.
TDR431 | Chalk talk | Best practices for containing AWS resources during incident response
Learn best practices for implementing isolation controls for AWS resources and accounts during security events. Through practical scenarios, discover effective approaches for isolating Amazon EC2 instances, AWS Lambda functions, and Amazon ECS containers. Explore comprehensive strategies for account-level isolation including identity, resource, and network controls. This session provides guidance on implementing and safely removing isolation controls as part of your response procedures. Leave with actionable patterns for strengthening your AWS incident response capabilities. To help businesses move faster and deliver security outcomes, modern security teams need to identify opportunities to automate and simplify their workflows. One way of doing so is through generative AI. Join this chalk talk to learn how to identify use cases where generative AI can help with investigating, prioritizing, and remediating findings from Amazon GuardDuty, Amazon Inspector, and AWS Security Hub. Then find out how you can develop architectures from these use cases, implement them, and evaluate their effectiveness. The talk offers tenets for generative AI and security that can help you safely use generative AI to reduce cognitive load and increase focus on novel, high-value opportunities.
TDR336 | Chalk talk | Secure generative AI models and agents on AWS
Learn how to strengthen security controls for generative AI models and Amazon Bedrock agents in your AWS environment. This session explores implementation patterns for protecting API endpoints and securing agent interactions. Discover practical approaches for implementing protective controls and maintaining data security for your AI/ML workloads. Leave with actionable strategies for building secure generative AI implementations using AWS services.
TDR337 | Chalk talk | Implementing AWS security best practices: Insights & strategies
Learn how to optimize your AWS security services implementation including Amazon GuardDuty, AWS Security Hub, and AWS WAF. AWS security experts share practical insights and proven patterns derived from thousands of customer deployments. This session provides actionable strategies for operationalizing security services effectively in your environment. Discover implementation best practices and architectural approaches that help you maximize the value of your AWS security services.
TDR338 | Chalk talk | Building cloud-native forensic investigation architectures on AWS
Join this chalk talk to explore the advantages of cloud-native digital forensics and incident response on AWS. Engage in interactive discussions on best practices for establishing secure forensic investigation environments. We’ll explore architectural patterns for safely collecting and storing forensic artifacts, leveraging ephemeral resources to enhance security, and implementing effective network, account, and organizational designs. Bring your questions and scenarios as we collaboratively examine how to build scalable, standardized investigation processes using AWS services. Leave with practical strategies for enhancing your forensic and incident response capabilities in the cloud.
TDR231 | Chalk talk | Resilient security teams: Reduce burnout and boost performance
Learn strategies for building resilient security and incident response teams that prioritize wellbeing while maintaining high performance. This session explores approaches for implementing regular team check-ins, data-informed wellbeing initiatives, and a supportive team culture. Discover practical methods for fostering open communication, maintaining team engagement, and recognizing team contributions. Through real-world examples, develop actionable plans to enhance team resilience, improve retention, and sustain security excellence. Leave with strategies to build and maintain high-performing security teams.
TDR321 | Lightning talk | From Incidents to Insights: Creating a Security Learning Organization
Learn how to transform security events into organizational improvements. This session demonstrates practical approaches for building effective feedback loops, preserving institutional knowledge, and implementing sustainable enhancements to security operations. Discover AWS strategies for measuring the impact of improvements and fostering a culture of continuous learning. Leave with actionable frameworks for strengthening your security program through systematic learning and adaptation.
TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.
TDR323 | Lightning talk | How Autodesk scales threat detection with Amazon GuardDuty
Learn how Autodesk elevated their threat detection strategy using Amazon GuardDuty. This lightning talk explores their implementation approach, operational insights, and best practices for leveraging the advanced detection capabilities of GuardDuty, including malware protection. Discover how they maintain robust security while efficiently managing their growing cloud footprint.
TDR421 | Lightning talk | Accelerating Incident Response with AWS Security Incident Response
Learn how AWS Security Incident Response helps security teams streamline investigation and response procedures. This session demonstrates service integration capabilities with Amazon GuardDuty, AWS CloudTrail, and AWS Security Hub to provide centralized incident management. Through customer examples and implementation patterns, discover practical approaches for building automated response strategies. Leave with actionable insights for enhancing your security operations using AWS services.
TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Discover how to build your first AI-powered security assistant using Amazon Q Business—no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application.
TDR252 | Builders’ session | Detect ransomware events in Amazon S3 using Amazon GuardDuty
In this builders’ session, join the AWS Customer Incident Response Team (CIRT) to implement Amazon S3 ransomware detection using Amazon GuardDuty. Through hands-on scenarios, learn to identify unauthorized encryption operations and implement effective response procedures. Build detection patterns using AWS CloudTrail, Amazon Athena, Amazon GuardDuty, and Amazon CloudWatch. Practice investigating events and implementing preventive measures aligned with AWS Security’s latest guidance for Amazon S3 object protection. You must bring your laptop to participate.
TDR351 | Builders’ session | Build an OCSF security log pipeline with AWS
Build a complete security log pipeline that leverages the Open Cybersecurity Schema Framework (OCSF) in this hands-on session. Work alongside AWS experts to ingest, transform, and enrich your security data. Learn practical techniques to standardize security logs, whether using your own schema or our provided examples. Walk away with implementable solutions to enhance your threat detection capabilities through normalized security data flows. Bring your laptop and optional custom log samples to create solutions tailored to your use cases.
TDR451 | Builders’ session | Automate incident response for Amazon EC2 and Amazon EKS
Learn how to streamline incident response using the Automated Forensics Orchestrator solution for Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Kubernetes Service (Amazon EKS). This session demonstrates how to implement automated workflows triggered by AWS Security Hub findings. Explore implementation prerequisites, customization options, and best practices for enhancing your security operations through automated forensics capabilities. Discover how to standardize response procedures across your Amazon EC2 and Amazon EKS environments.
TDR452 | Builders’ session | Build generative AI security runbooks with Amazon Bedrock
In this builders’ session, learn how to enhance security operations using generative AI-powered runbooks with Amazon Bedrock and Bedrock Agents. Create intelligent workflows that analyze AWS Security Hub findings and provide contextual remediation guidance. Through hands-on exercises, build Bedrock Agents that leverage AWS documentation and implement natural language interfaces for security investigations. Learn how to configure knowledge bases with organization-specific content and implement appropriate guardrails. Leave with a practical solution for streamlining security operations using generative AI. You must bring your laptop to participate.
TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Security Lake
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.
TDR342 | Code talk | Operationalizing Amazon Security Lake with analytics and generative AI
Roll up your sleeves for this hands-on coding session where we’ll build modern security analytics tools on top of Amazon Security Lake. Through interactive demos, we’ll craft queries and visualizations to operationalize your security data using AWS services like Amazon OpenSearch Service, Amazon QuickSight, Amazon Athena, and Amazon Bedrock. Leave with practical code samples and architectures to analyze security data. Get inspired with ideas on how to transform your threat detection and incident response stack.
TDR343 | Code talk | From detection to code: GuardDuty attack sequences with Amazon Q
In this code talk, explore how Amazon GuardDuty attack sequence detection capabilities work alongside Amazon Q to enhance security operations. Through live coding demonstrations, learn hoGuardDuty machine learning models identify connected security events and create comprehensive event sequences. See how to build automated response procedures using Amazon Q AI-assisted development capabilities. Discover practical approaches for implementing context-aware security automation. Leave with implementation patterns for enhancing your security operations using generative AI tools.
TDR371 | Workshop | Hands-on Threat Detection & Response using AWS Security
Get hands-on experience with AWS security services in this interactive workshop. Learn to detect and respond to simulated threats using Amazon GuardDuty, Amazon Inspector, AWS Security Hub, and Amazon Detective. Practice both manual and automated response techniques with AWS Lambda as you investigate security events across different resource types. Walk away with practical skills to operationalize threat detection and response in your AWS environment. Bring your laptop to participate in this hands-on workshop.
TDR372 | Workshop | Secure container workloads with AWS security services
In this workshop, learn how to implement AWS security services to protect container workloads end-to-end from code to operations. Gain hands-on experience with static code analysis, detective controls, threat detection, vulnerability management, and incident response for Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS). Through guided scenarios, discover how to use AWS security services to enhance your container security posture. Leave with practical strategies for implementing security controls in your container environments. You must bring your laptop to participate.
TDR471 | Workshop | AWS Security Incident Response Challenge: Defense in action
Put your AWS security incident response skills to the test in this interactive session. Assume the role of an AWS Security Engineer responding to a time-sensitive scenario. Using provided intelligence, you’ll have a limited time to implement security controls in your AWS environment. Learn to prioritize actions and leverage AWS security services effectively under realistic conditions. This hands-on exercise helps you practice rapid decision-making and security implementation in AWS environments. Leave with practical experience in incident response strategies. You must bring your laptop to participate.
TDR472 | Workshop | Active defense strategies using AWS AI/ML services
This workshop will help you learn how to develop and deploy active defense strategies, such as deception, using Amazon Bedrock and Amazon SageMaker. Gain hands-on experience developing AI-driven responses for security operations. You will learn how to develop adaptive responses that mimic what an actor may be trying use against you. You will Learn implementation patterns for prompt engineering, deployment strategies, and monitoring methodologies. You must bring your laptop to participate.
Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus gamified learning, innovation sessions, partner sessions, and labs. Discover how to optimize your re:Inforce journey with our attendee guides—your essential resource for selecting perfect learning sessions and getting the greatest value from your experience.
Our comprehensive track content is designed to help arm you with the knowledge and skills needed to securely manage your workloads and applications on AWS. Don’t miss out on the opportunity to stay updated with the latest best practices in threat detection and incident response. Join us in Philadelphia for re:Inforce 2025 by registering today. We can’t wait to welcome you!
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Post Syndicated from jake original https://lwn.net/Articles/1021871/
Cory Doctorow wears many hats:
digital activist, science-fiction author, journalist, and more. He has
also written many books, both fiction and non-fiction, runs the Pluralistic blog, is a visiting
professor, and is an advisor to the Electronic
Frontier Foundation (EFF); his Chokepoint Capitalism
co-author, Rebecca Giblin, gave a 2023 keynote
in Australia that we covered. Doctorow gave a rousing keynote on
the state of the “enshitternet”—today’s internet—to kick
off the recently held PyCon US
2025 in Pittsburgh, Pennsylvania.
Post Syndicated from Emma Burdett original https://blog.rapid7.com/2025/05/27/retail-under-siege-what-recent-cyber-attacks-tell-us-about-todays-threat-landscape/

When several major UK organizations, including well-known retail brands, found themselves caught in a cyber attack earlier this year, it made headlines. But this incident wasn’t the first, and it won’t be the last. It reflects a growing trend where attackers exploit third-party vendors to breach multiple businesses through a single point of entry.
In one case, the compromise stemmed from a vulnerability in MOVEit Transfer, a widely used file transfer tool. Attackers exploited the flaw through Zellis, a payroll provider servicing organisations such as Boots, the Co-op, and parts of the NHS. From that single access point, they were able to exfiltrate sensitive employee data, including names, dates of birth, national insurance numbers, and in some cases, bank details. Some customer data was also affected, although not financial information.
This wasn’t just a breach. It was a blueprint—and a clear signal that even the most trusted brands are vulnerable when third-party risk is left unaddressed.
The MOVEit vulnerability, first exposed in mid-2023, has become a favoured entry point for criminal groups looking to conduct high-volume, high-impact attacks. In this instance, attackers reportedly linked to the group Scattered Spider moved quickly, exploiting the flaw to access data at scale.
They didn’t need to phish credentials, crack passwords, or trick users. They found a vulnerable service buried in the supply chain and used automation and speed to do the rest.
This type of breach is becoming alarmingly common. Attackers increasingly target third-party software and services, i.e. vendors with connections to dozens or hundreds of organisations, because it maximises the potential return on effort. Instead of breaching one business at a time, they go upstream and compromise a shared dependency.
Scattered Spider in particular has shown a keen focus on the retail sector, where high transaction volumes, rich identity data, and complex supply chains create an attractive threat surface. As noted in Dark Reading, these groups are playing the long game—building persistent access, quietly exfiltrating data, and returning to monetise later.
This is third-party risk in action. And it’s only becoming more sophisticated.
Rapid7’s threat intelligence teams have tracked how ransomware groups and data extortion crews have professionalised their operations over the past two years. These groups are no longer operating in the shadows. They’re mimicking enterprise structures, with revenue sharing models, support desks, marketing channels, and on-demand tooling.
Groups like DragonForce, for instance, use a white-label ransomware-as-a-service model built on LockBit code, offering affiliates a fully managed platform for launching attacks. As Raj Samani, SVP and Chief Scientist at Rapid7, noted in recent research, these groups provide their affiliates with everything they need to run sophisticated campaigns: prebuilt infrastructure, encryption tools, data leak sites, and communication channels. Their tactics often involve dual extortion – stealing data and threatening to publish it unless a ransom is paid, adding public pressure to the private pain of a breach.
This business-like approach is exactly why ransomware remains one of the most dominant threats in 2025. Ransomware today is less about disruption and more about strategy. Our recent analysis explores how these attacks have evolved from smash-and-grab to long-game economics, with extortion tactics designed to exert maximum pressure over time.
But the financial hit is only one part of the damage. As Raj explores in this piece for the Cyber Threat Alliance, the broader impact of cybercrime often goes uncounted—from reputational fallout and operational disruption to the long-term toll it takes on people and trust. These are the consequences organisations must now plan for, not just respond to.
These tactics are playing out across the retail sector and beyond. Attackers are using known exploits, moving efficiently, and causing maximum disruption—not by inventing new techniques, but by taking advantage of weaknesses businesses continue to overlook.
The obvious takeaway is that third-party risk is real, and growing. But there’s a deeper issue beneath the surface: many organisations lack the visibility they need to see where their risk truly lies.
As we’ve argued before, proactive visibility is foundational to strong cybersecurity. If you don’t have a live, accurate view of your external exposure across infrastructure, vendors, applications, and user behaviour, you’re already behind. And if you don’t understand how your systems interact with those of your partners, you can’t realistically assess the blast radius of a third-party breach.
This is where a Continuous Threat Exposure Management (CTEM) approach is essential. CTEM isn’t about reacting to every vulnerability alert. It’s about identifying which exposures are most likely to be exploited and putting the processes in place to resolve them before attackers take advantage.
That means:
The goal isn’t perfection. It’s preparedness.
The real takeaway for security leaders isn’t “this could happen to us.” It’s the recognition that some version of this is already happening—whether they know it or not.
Attackers are scanning your environment. They’re probing your vendors. They’re replaying leaked credentials and looking for unpatched services. What they find, and how quickly you detect and respond defines the outcome.
This is why we encourage organisations to move from reactive defence to proactive control. You don’t need to boil the ocean. But you do need a plan that accounts for real-world attacker behaviour, not just compliance checklists.
At Rapid7, we advocate for a layered, risk-informed approach. That includes:
But more than any product or service, the most important element is mindset. Security is no longer something you install or outsource. It’s something you practice every day, across every level of the business.
Breaches like this one also raise important questions for consumers.
As Rapid7 CTO EMEA Thom Langford recently pointed out, individuals can take practical steps to reduce their risk. That includes using a password manager to store strong, unique passwords, enabling multi-factor authentication (MFA), and avoiding the storage of card details in retail accounts. For frequent online shoppers, virtual or disposable cards offer an extra layer of protection.
Still, the burden cannot rest on individuals alone. Organisations must design systems that make secure choices the default. That means encrypting data at rest and in transit, enforcing MFA by default, and never storing sensitive credentials in plaintext.
In a hyper-connected digital economy, trust is everything. And trust is built through transparency, responsiveness, and consistent investment in security—even when there’s no breach in the headlines.
These attacks aren’t happening because a single business made a mistake. They’re happening because attackers are evolving and because the systems we all rely on are more interconnected than ever.
Security leaders can’t control every vendor or patch every flaw in someone else’s software. But they can control how they prepare, how they prioritise, and how they respond.
The organisations that come out stronger are the ones that treat security as a continuous discipline – one rooted in visibility, resilience, and readiness.
Because in 2025, the question isn’t whether you’ll be targeted.
It’s whether you’ll be ready.
Post Syndicated from corbet original https://lwn.net/Articles/1022704/
Version
25.05 of the NixOS distribution has been released. Changes include
support for the COSMIC desktop environment (reviewed here in August), GNOME 48, a
6.12 kernel, and many new modules; see the
release notes for details. (Thanks to Pavel Roskin).
Post Syndicated from corbet original https://lwn.net/Articles/1022703/
Security updates have been issued by AlmaLinux (gstreamer1-plugins-bad-free, libsoup, and python-tornado), Debian (libavif and pgbouncer), Red Hat (gstreamer1-plugins-bad-free, mingw-freetype and spice-client-win, and webkit2gtk3), SUSE (firefox, govulncheck-vulndb, and python310-setuptools), and Ubuntu (flask, intel-microcode, openjdk-17-crac, tika, and Tomcat).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/05/chinese-owned-vpns.html
One one my biggest worries about VPNs is the amount of trust users need to place in them, and how opaque most of them are about who owns them and what sorts of data they retain.
A new study found that many commercials VPNS are (often surreptitiously) owned by Chinese companies.
It would be hard for U.S. users to avoid the Chinese VPNs. The ownership of many appeared deliberately opaque, with several concealing their structure behind layers of offshore shell companies. TTP was able to determine the Chinese ownership of the 20 VPN apps being offered to Apple’s U.S. users by piecing together corporate documents from around the world. None of those apps clearly disclosed their Chinese ownership.
Post Syndicated from Laura Kirsop original https://www.raspberrypi.org/blog/beyond-phone-bans-empowering-students-to-critically-navigate-and-reimagine-technology/
Amidst heated discussion of smartphones and their impacts on young people’s lives, it’s become a frequent recommendation to ban phones in schools. Below I summarise the research evidence on smartphone bans (it’s mixed) and share tips for computing educators on how to constructively address the topic with their learners and empower them to think critically about technology design.
2024 was the year the tide turned against smartphones. Across the world, parents, teachers, and governments highlighted the risks of excessive phone use among young people. In the UK, the ‘Smartphone Free Childhood’ movement emerged, quickly growing to 100,000 members who advocate for keeping smartphones away from children due to concerns about addiction, harmful content, and mental health. Jonathan Haidt’s global bestseller The Anxious Generation has further fuelled the movement, linking smartphone use to adolescent mental health issues and recommending phonefree schools. Meanwhile, countries including England, France, and Finland have urged schools to adopt strict phone bans, hoping to reduce classroom distractions and enhance student safety.
Despite widespread support, academic research on phone bans remains limited and inconclusive. Given this situation, computing educators are uniquely positioned to offer an alternative approach.
The rapid spread of school smartphone bans is a straightforward response to complex issues around personal technology use in education. Teachers and parents frequently view phones as inherently disruptive, a perspective supported by studies that show phones can impair students’ focus and engagement in lessons. Concerns about cyberbullying and addiction contribute to this view, with many educators seeing bans as a practical solution to mitigate risks. Surveys in England reveal that nearly half of all secondary schools now enforce all-day bans. This trend was supported by teachers participating in my master’s degree research, who see these policies as necessary to reduce distractions and maintain control in the classroom.
“Calls for outright bans may oversimplify the conversation.”
Yet calls for outright bans may oversimplify the conversation, limiting opportunities to examine both the benefits and the risks of smartphone use in schools. Evidence on the impact of phone restrictions is mixed: while some studies suggest restrictions may benefit learning, especially for students who struggle the most, others indicate no significant impact on academic outcomes. Additionally, recent findings show that cyberbullying is not directly linked to time spent online, with traditional bullying still more prevalent in schools. Even the narrative around smartphone addiction is contested, with some researchers suggesting that concerns about addiction may be overstated. And some places schools do not have access to digital devices for learners and then smartphones may play a crucial role in teaching and learning digital literacy skills.
As the debate over smartphone bans continues, educators have an opportunity to move beyond restrictions and engage students in understanding the technology that shapes their lives. This is where computing educators can really make a difference. How can they guide students to understand why technology is designed to capture attention and what lies behind these design choices?
School smartphone bans can feel like a hopeless act that suggests phones and social media are inherently incompatible with learning and student well-being. This approach assumes the only solution is to remove them, rather than considering how these technologies might be better managed or reimagined to support young people. What if, instead of banning phones, educators worked with students to explore why they are so captivating and how they could be designed differently? Computing educators can lead this exploration. With digital literacy as part of their curriculum, computing teachers can help students question the motives behind their devices, fostering a critical understanding of the forces shaping their digital world.
“With digital literacy as part of their curriculum, computing teachers can help students question the motives behind their devices, fostering a critical understanding of the forces shaping their digital world.”
At the heart of how social media platforms are designed is their business models. Tech companies rely on features such as notifications, autoplay, and infinite scrolling to maximise user engagement and revenue. This is part of what the writer Shoshana Zuboff calls “surveillance capitalism”, where companies gather vast amounts of behavioural data by keeping users engaged on their platforms for as long as possible.
In the classroom, educators can open discussions with students on the motives behind technology design, exploring questions such as why platforms want users to stay engaged, and what data they are collecting. Activities might include analysing popular apps to identify which features encourage prolonged use, or debating how social media could be designed to prioritise user wellbeing. By critically examining these design choices, students can better understand the forces driving their digital interactions and consider ways in which technology could be reimagined to serve them, rather than just profiting from them.
Once young people understand why phones and social media are designed the way they are, educators can work with students to create phone policies that reflect shared values and goals. This collaborative approach encourages students to take ownership of their technology use, and computing teachers, drawing on their knowledge of technology design and digital literacy, are ideally positioned to facilitate these discussions.
Research suggests that policies developed with student input are more effective, as they foster responsibility and engagement. By involving students in policymaking, educators can encourage them to consider how phones could support rather than hinder learning. For example, students might agree that phones should stay off during certain times, or in certain spaces, but that they might be useful in other scenarios where access benefits learning. This kind of flexibility ensures that phones are used thoughtfully, allowing for both practical boundaries and opportunities for educational use.
As debate around smartphone use in schools continues, academic research remains inconclusive on the effectiveness of phone bans. This uncertainty presents computing educators with an opportunity to move beyond restrictive policies and foster deeper understanding. By guiding students to explore why phones and social media are designed to capture attention, we can help to equip them with the critical skills needed to navigate their digital world thoughtfully. Involving students in crafting flexible, meaningful phone policies reinforces this understanding, giving them a sense of agency in shaping technology’s role in their lives.
Computing educators are uniquely positioned to empower students, not just as users, but as active challengers of technology design norms. Embracing a collaborative approach allows computing educators to inspire students to envision a future where technology genuinely serves their growth and their learning, rather than commercial interests.
A version of this article appears in the newest issue of Hello World magazine, which is all about teaching digital literacy. Explore issue 26 and download your free PDF copy today.
You can also listen to our recent Hello World podcast episode discussing the myth of the ‘digital native’ and whether today’s young people are tech-savvy or tech-dependent.
The post Beyond phone bans: Empowering students to critically navigate and reimagine technology appeared first on Raspberry Pi Foundation.
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=oYy7zu0JgEo