Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=f4KA_TTN8NU
Cross-account data collaboration with Amazon DataZone and AWS analytical tools
Post Syndicated from Arun Pradeep Selvaraj original https://aws.amazon.com/blogs/big-data/cross-account-data-collaboration-with-amazon-datazone-and-aws-analytical-tools/
Data sharing has become a crucial aspect of driving innovation, contributing to growth, and fostering collaboration across industries. According to this Gartner study, organizations promoting data sharing outperform their peers on most business value metrics. A straightforward data access and sharing mechanism is crucial for enabling effective data sharing across an organization. There are challenges such as complexity in managing cross-account permissions and difficulty in discovering the right data across accounts that organizations face when trying to share data products across AWS accounts. Amazon DataZone is a fully managed data management service that customers can use to catalog, discover, share, and govern data stored across Amazon Web Services (AWS).
In this post, we will cover how you can use Amazon DataZone to facilitate data collaboration between AWS accounts.
Solution overview
This solution provides a streamlined way to enable cross-account data collaboration using Amazon DataZone domain association while maintaining security and governance. This post describes the process of using the business data catalog resource of Amazon DataZone to publish data assets so they’re discoverable by other accounts. After they’ve been published, you can query the published assets from another AWS account using analytical tools such as Amazon Athena and the Amazon Redshift query editor, as shown in the following figure.

In this solution (as shown in the preceding figure), the AWS account that contains the data assets is referred to as the producer account. The AWS account that needs to access or use the data from the producer account is referred to as the consumer account. The Amazon DataZone domain is created and managed within the producer account and then the consumer account is associated with that domain.
As part of Amazon DataZone domain association, Amazon DataZone uses AWS Resource Access Manager (AWS RAM) to share the resource. When the producer and consumer AWS accounts are in the same organization within AWS Organizations, the domain association happens automatically. If the producer and consumer AWS accounts are in different organizations, AWS RAM sends an invitation to the consumer AWS account to accept or reject the resource grant.
This solution presents three Amazon DataZone user personas as:
- Data administrators: Account owners in both producer and consumer AWS accounts. The data administrators are responsible for creating Amazon DataZone domains, configuring domain associations, and accepting domain associations within the Amazon DataZone domain.
- Data publishers: Users in producer AWS accounts. The data publishers are responsible for creating Amazon DataZone publish projects and environments, producing and publishing data assets, and accepting subscription requests.
- Data subscribers: Users in consumer AWS accounts. The data subscribers are responsible for creating Amazon DataZone subscribe projects and environments, searching for and subscribing to data assets, and querying the data and deriving insights.
Prerequisites
To follow along with the instructions, you will need:
- Two AWS accounts, one serving as producer and other account serving as consumer. Create new AWS accounts if necessary.
- An Amazon Redshift provisioned cluster or Amazon Redshift Serverless workgroup in the producer and consumer AWS accounts provisioned by a data administrator.
- A secret in AWS Secrets Manager storing the master user credentials for the Amazon Redshift cluster or workgroup in the producer and consumer AWS accounts.
- The data administrators are responsible for creating secrets.
- The data producers and consumers can obtain the Amazon Resource Name (ARN) of the secrets from the data administrators during the environment or environment profile creation steps.
Amazon DataZone uses Amazon Redshift Datashares to share data across clusters and accounts. There are specific requirements and limitations for using Amazon Redshift datashares.
- For cross-account data sharing, both the producer and consumer clusters must be encrypted. See Cluster encryption section of datashare-considerations for more information about the encryption process.
- Data sharing is supported only for provisioned ra3 cluster types (ra3.16xlarge, ra3.4xlarge, and ra3.xlplus) and Amazon Redshift Serverless.
Walkthrough:
The following are the high level steps to configure cross-account access. We’ve provided step-by-step instructions in the following sections.
- Create an Amazon DataZone domain in the producer account. The data administrator creates an Amazon DataZone domain.
- Request Amazon DataZone domain association from the producer account to the consumer account.
- Accept the domain association request in the consumer account. The data administrator accepts the domain association.
- Add data users to the Amazon DataZone domain.
- Create the necessary publish project for AWS Glue and Amazon Redshift in the producer account.
- Create AWS Glue and Amazon Redshift environments to publish the data assets in the producer account.
- Create and run a data source for AWS Glue and Amazon Redshift to publish assets into the business catalog.
- Create subscribe projects for AWS Glue and Amazon Redshift.
- Create AWS Glue and Amazon Redshift environment profiles and environments in the subscribe project
- Subscribe to AWS Glue and Amazon Redshift tables. Consume the data using Athena and Amazon redshift editors. This step is performed by the data subscriber.
Create the Amazon DataZone domain in the producer account
Amazon DataZone domains serve as high-level organizational units for assets, users, and projects, facilitating cross-team and cross-account collaboration. This step focusses on creating the Amazon DataZone domain in the producer account.
- Sign in to the producer account AWS Management Console for Amazon DataZone using the data administrator credentials.
- Create an Amazon DataZone domain titled
Demo_cross_account_domainusing the instructions at create domains. - On the Create domain screen, select Quick setup checkbox to automate several configuration steps, saving time and reducing the potential for setup errors. Quick setup enables two default blueprints and creates the default environment profiles for the data lake and data warehouse default blueprints.


Request Amazon DataZone domain association from the producer account to the consumer account
To associate the Amazon DataZone domain with the consumer account, the producer account requests a domain association. This involves providing necessary information about the consumer account and granting appropriate permissions for data access and management.
- Sign in to the Amazon DataZone console of the producer account using the data administrator credentials.
- Navigate to the domain detail page, and then scroll down and select the Associated Accounts tab.
- Enter the consumer account IDs that you want to request association. Choose Add another account if you want to add more than one account. When you’re satisfied with the list of account IDs, choose Request association.
- Use the latest (AWS RAM
DataZonePortalReadWritepolicy when requesting the account association. This policy allows users in the consumer account to execute Amazon DataZone APIs and to use the data portal interface.
- Use the latest (AWS RAM

Accept an account association request from an Amazon DataZone domain
This step focuses on accepting the account association request from the Amazon DataZone domain in the consumer account. This allows the consumer account to be linked with the Amazon DataZone domain to enable data sharing and collaboration between the producer and consumer accounts.
- Sign in to the consumer account and go to the Amazon DataZone console in the same AWS Region as the domain. On the Amazon DataZone home page, choose View requests.
- Select the name of the inviting Amazon DataZone domain and choose Review request.
- Choose Accept association, you should see the
Demo_cross_account_domainstate as associated in the Associated domains screen

- Choose the domain for which you want to enable an environment blueprint.
- From the Blueprints list, choose either the DefaultDataLake blueprint
- On the Permissions and resources page, for enabling the DefaultDataLake blueprint, for Glue Manage Access role, specify a new role that grants Amazon DataZone authorization to ingest and manage access to tables in AWS Glue and AWS Lake Formation.

- Repeat steps 4 to 6 to enable the DefaultDataWarehouse blueprint by choosing DefaultDataWarehouse instead of DefaultDataLake

Add data users to the Amazon DataZone domain
To grant access to the Amazon DataZone data portal from the console for data publisher and data Subscriber IAM users, use the following steps to add them in the User Management section of the Amazon DataZone domain. See Manage users in the Amazon DataZone console for additional details.
- Sign in to the Amazon DataZone console as a data administrator using the producer account.
- Select the Amazon DataZone domain and, in the User management section, choose Add and select Add IAM users.

- On the Add users page, choose Current account and add the user ARN of the data producer and choose Add users.

- Next choose Associated account, and enter the data subscriber user’s ARN and add the user by choosing Add users.


Create the publish project for AWS Glue and Amazon Redshift
This step focuses on creating the publish project for AWS Glue and Amazon Redshift in the producer account. The project will be used to publish data from your data sources to the appropriate AWS services.
- Using the producer account, sign in to the Amazon DataZone console as a data publisher.
- Select View domains and select the demo_cross_account_domain.
- Choose the Open data portal link and sign in to the data portal.
- Choose Create New Project and create a project named
Glue_Publish_Projectfor publishing AWS Glue data assets and create the project under demo_cross_account_domain.
- Create another project named
Redshift_Publish_Projectfor publishing Amazon Redshift data assets, also under the demo_cross_account_domain.


Create AWS Glue and Amazon Redshift environments to publish the data assets
In this step, you set up AWS Glue and Amazon Redshift environments in the producer account to share data assets. The required infrastructure, such as the AWS Glue Data Catalog and Redshift cluster for storing data, should already be in place. After setup, this will allow the consumer account to access and use the shared data assets. See Create a new environment for detailed instructions on creating a new environment.
Create the AWS Glue environment and a new AWS Glue table
- In the same Amazon DataZone domain demo_cross_account_domain, choose Browse Project and select the Glue_Publish_Project and create Glue_Publish_Environment using the default DataLakeProfile.
- Leave the producer_glue_db_name, consumer_glue_db_name and Workgroup_name blank.
- Choose Create Environment and wait for the process to complete.

- After the environment is created, browse the list of available projects and choose Glue_publish_project.
- Next, navigate to the Glue_Publish_Environment, and under Analytics tools, choose Amazon Athena to open the Athena query editor

- Choose Open Athena and make sure that Glue_Publish_Environment is selected in the Amazon DataZone environment dropdown at the upper right and that in Data on the left, glue_publish_environment_pub_db is selected as the Database.

- Create a new AWS Glue table for publishing to Amazon DataZone. Paste the following create table as select (CTAS) query script in the Query window and run it to create a new table named
mkt_sls_table. The script creates a table with sample marketing and sales data.CREATE TABLE mkt_sls_table AS SELECT 146776932 AS ord_num, 23 AS sales_qty_sld, 23.4 AS wholesale_cost, 45.0 as lst_pr, 43.0 as sell_pr, 2.0 as disnt, 12 as ship_mode,13 as warehouse_id, 23 as item_id, 34 as ctlg_page, 232 as ship_cust_id, 4556 as bill_cust_id UNION ALL SELECT 46776931, 24, 24.4, 46, 44, 1, 14, 15, 24, 35, 222, 4551 UNION ALL SELECT 46777394, 42, 43.4, 60, 50, 10, 30, 20, 27, 43, 241, 4565 UNION ALL SELECT 46777831, 33, 40.4, 51, 46, 15, 16, 26, 33, 40, 234, 4563 UNION ALL SELECT 46779160, 29, 26.4, 50, 61, 8, 31, 15, 36, 40, 242, 4562 UNION ALL SELECT 46778595, 43, 28.4, 49, 47, 7, 28, 22, 27, 43, 224, 4555 UNION ALL SELECT 46779482, 34, 33.4, 64, 44, 10, 17, 27, 43, 52, 222, 4556 UNION ALL SELECT 46779650, 39, 37.4, 51, 62, 13, 31, 25, 31, 52, 224, 4551 UNION ALL SELECT 46780524, 33, 40.4, 60, 53, 18, 32, 31, 31, 39, 232, 4563 UNION ALL SELECT 46780634, 39, 35.4, 46, 44, 16, 33, 19, 31, 52, 242, 4557 UNION ALL SELECT 46781887, 24, 30.4, 54, 62, 13, 18, 29, 24, 52, 223, 4561
- Go to the Tables and Views section and verify that the
mkt_sls_tabletable was successfully created.


Create the Amazon Redshift publish environment and a new Redshift table
- Staying in the same Amazon DataZone domain demo_cross_account_domain, choose Browse Project, to create an Amazon Redshift publish environment, select the Redshift_Publish_Project and create Redshift_Publish_Environment using the default data warehouse profile.
- To configure environment parameters, enter the name of your Amazon Redshift cluster or workgroup, specify the database name and enter the AWS Secrets Manager secret ARN for the Redshift cluster or workgroup. You need to make sure that the secret in Secrets Manager includes the following tags. These tags help Amazon DataZone implement proper access control so that only authorized users within the correct Amazon DataZone project and domain can access the Amazon Redshift resource:
- For Amazon Redshift cluster:
DataZone.rs.cluster: <cluster_name:database name> - For Amazon Redshift Serverless workgroup:
DataZone.rs.workgroup: <workgroup_name:database_name> - AmazonDataZoneProject:
<projectID> - AmazonDataZoneDomain:
<domainID>For more information for creating redshift database user secret in secret manager, see Storing database credentials in AWS Secrets Manager.
- For Amazon Redshift cluster:
For more information for creating redshift database user secret in secret manager, see Storing database credentials in AWS Secrets Manager.
- Note that the database user you provide in Secrets Manager must have superuser permissions. Data publishers should work with the data administrator to get the details of the Redshift cluster or workgroup, database name, and secret ARN.
- The schema is optional.
- Choose Create Environment and wait for the process to complete.

- Verify that the environment is created successfully without errors.
- Browse the list of available projects and select
Redshift_publish_project. Navigate toRedshift_publish_environment. - Under Analytics tools, choose Amazon Redshift to open the Amazon Redshift query editor.
- Select the Redshift cluster that you want to connect, choose Save and then choose Create Connection using temporary credentials with your IAM identity.

- Create a new Redshift table. You can use the CTAS query to create a new table named
rs_sls_tbl. Use the provided CTAS script, which creates a table with sample sales data in thedatazone_env_redshift_publish_environmentschema. - Make sure that the
rs_sls_tbltable is successfully created.


Publish assets into the common business catalog
In this step, you create and run the Amazon DataZone data sources for AWS Glue and Amazon Redshift. You will then publish the data assets from these data sources.
The Amazon DataZone data sources allow you to connect to various data sources, including databases, data warehouses, and data lakes, and ingest metadata into Amazon DataZone. By creating and running these data sources, you can make your data available for analysis, transformation, and sharing within your organization.
After the data sources are set up, you can publish the data assets from these sources to make them accessible to other users and applications. This process involves mapping the data assets to the appropriate business terms and metadata, making sure that the data is properly described and categorized.
Add an AWS Glue data source to publish the new AWS Glue table.
- Stay signed in the producer account and Amazon DataZone console as a data publisher.
- Choose Select project from the top navigation pane and select the Glue_Publish_Project that you want to add the data source to.
- Select the Glue_Publish_Environment.
- Choose Create data source. Enter
glue-publish-datasourceas the name. - Under Data source type, choose AWS Glue.
- Under Select an environment, select Glue_Publish_Environment.
- Under Data selection, select the AWS Glue database glue_publish_environment_pub_db, enter your table selection criteria as “*“, and then and choose Next.
- Leave all other setting as default and choose Next.
- For Run Preference, select Run on demand to ingest metadata from the specified AWS Glue tables into Amazon DataZone.
- Review and choose Create.
- After the data source has been created choose Run. The
mkt_sls_tablewill be listed in the inventory and available to publish.
- Select the
mkt_sls_tabletable and review the metadata that was generated. Choose Accept All if you’re satisfied with the metadata.
- Choose Publish Asset and the
mkt_sls_tabletable will be published to the business data catalog, making it discoverable and understandable across your organization.


Add an Amazon Redshift data source to publish the new Amazon Redshift table.
- Stay signed in the producer account and Amazon DataZone console as a data publisher.
- Choose Select project from the top navigation pane and select the Redshift_Publish_Project that you want to add the data source to.
- Choose the Redshift_Publish_Environment.
- Choose Create data source. Enter
rs-publish-datasourceas the name. - Under Data source type, select Amazon Redshift.
- Under Select an environment, select Redshift_Publish_Environment.
- Under Redshift Credentials, enter the Redshift cluster and secret details provided by the data administrator.
- Under Data Selection, select the database dev and schema datazone_env_redshift_publish_environment.
- Keep other setting as default and choose Next.
- For Run Preference, select Run on Demand.
- Choose Save. After the data source is created, choose Run. The data source runs and the
rs_sls_tblwill be listed in the inventory and available to publish.
- Select the
rs_sls_tbltable and review the metadata that was generated. Choose Accept All if you are satisfied with the metadata.
- Choose Publish Asset and the
rs_sls_tabletable will be published to the business data catalog.


Create subscribe projects for AWS Glue and Amazon Redshift
In this step, you create the projects for subscribing to AWS Glue and Amazon Redshift data assets within your Amazon DataZone domain.
- Sign in to the Amazon DataZone console as a data subscriber IAM user using the consumer account.
- Choose Associated domains and select the demo_cross_account_domain.
- Select the Open data portal link and sign in to the data portal.
- Choose Create New Project and create a project named
Glue_Subscribe_Projectfor subscribing to the AWS Glue data assets. - Create another project named
Redshift_Subscribe_Projectfor subscribing to the Redshift data assets.
Create AWS Glue and Amazon Redshift environment profiles
In this step, you will set up the environment profiles and environments for AWS Glue and Amazon Redshift in your Amazon DataZone projects. This will allow you to connect and interact with resources across AWS accounts.
The purpose of environment profiles in Amazon DataZone is to streamline the process of environment creation. By using environment profiles, you can preconfigure essential placement information such as AWS account and AWS Region. In this solution, you will configure environment profiles with placement information pointing to your consumer account.
You will also create an Amazon DataZone environment from the profiles you are about to create. This will provision the necessary resources in the consumer account and establish the connections between the Amazon DataZone domain and the consumer account. After the environments are created, you can work with AWS Glue and Amazon Redshift assets seamlessly across different AWS accounts within your Amazon DataZone ecosystem.
Create an AWS Glue profile and environment
- Stay signed in the consumer account’s Amazon DataZone console as a data subscriber IAM, select the Environments tab and then choose Create environment profile.
- Configure the fields as follows:
- Name: Enter
glue_subscribe-env-profile. - Owner: The project where the profile is being created is selected by default in this field. Verify that it’s
Glue_Subscribe_Project. - Blueprint: Select Default Data Lake.
- AWS account parameters: Enter the consumer AWS account number and select the Region.
- Authorized projects: Select All projects.
- Publishing: Select Publish from any database.
- Choose Create Environment Profile.


- Name: Enter
- On the Create environment page, enter the following:
- Name: Enter
glue_subscribe_environment. - Verify that the Environment profile is set to glue_subscribe-env-profile.
- Name: Enter
- (Optional) Parameters: Enter the Producer glue db name, Consumer glue db name, and Workgroup name.
- Choose Create environment.

- It takes a few minutes for the environment to be created. Verify that the environment creation is successful without any errors.


Create a Redshift environment profile and environment
- Staying in the consumer account’s Amazon DataZone management console as a data subscriber IAM user, navigate to the Redshift_Subscribe_Project you created previously.
- Select the Environments tab and then choose Create environment profile.
- Configure the fields as follows:
- Name: Enter
redshift_subscribe-env-profile. - Owner: Verify that Project is set to Redshift_Subscribe_Project.
- Blueprint: Select Default Data Warehouse.
- Parameter set: Select Enter my own.
- AWS account parameters: Enter the consumer AWS account number and select the Region.
- Parameters: Select either Amazon Redshift Cluster or Amazon Redshift Serverless in the consumer account.
- AWS Secret ARN: Enter the AWS Secrets Manager secret ARN for the Redshift cluster or workgroup. You need to make sure that the secret in Secrets Manager includes the following tags. These tags help Amazon DataZone implement proper access control so that only authorized users within the correct Amazon DataZone project and domain can access the Amazon Redshift resource.
- AmazonDataZoneDomain: [
Domain_ID] - AmazonDataZoneProject: [
Project_ID]
- AmazonDataZoneDomain: [
For more information for creating redshift database user secret in secret manager, see Storing database credentials in AWS Secrets Manager.
Note that the database user you provide in AWS Secrets Manager must have superuser permissions. Data publishers should work with the data administrator to get the details of the Redshift cluster or workgroup, database name, and secret ARN.
- Redshift cluster name: Enter the name of the Amazon Redshift cluster or Amazon Redshift Serverless workgroup.
- Database name: Enter the name of the database within the selected Amazon Redshift cluster or Amazon Redshift Serverless workgroup
- AWS Secret ARN: Enter the AWS Secrets Manager secret ARN for the Redshift cluster or workgroup. You need to make sure that the secret in Secrets Manager includes the following tags. These tags help Amazon DataZone implement proper access control so that only authorized users within the correct Amazon DataZone project and domain can access the Amazon Redshift resource.
- Authorized projects: Select All projects.
- Publishing: Select Publish any schema.
- Name: Enter
- Choose Create environment profile.


- Create an environment from this profile: Create an environment from this profile:
- Name: Enter
redshift_subscribe_environment. - Verify that the Environment profile is set to redshift_subscribe-env-profile.
- Name: Enter
- Choose Create Environment.


It takes a few minutes for the environment to be created. Verify that the environment creation is successful without any errors.

Subscribe to the AWS Glue and Redshift tables
In this step, you will subscribe AWS Glue and Amazon redshift tables published by the data producer.
Subscribe to the AWS Glue table
- Sign in to the Amazon DataZone console of the consumer account using the data subscriber credentials and navigate to the Glue_Subscribe_project you created previously.
- Search for the Market Sales Table in the Search bar.

- Select the Market Sales Table and choose Subscribe.
- In the Subscribe pop-up window, provide the following information:
- Project: Enter the name of the project that you want to subscribe to the asset. By default this will be Glue_Subscribe_Project.
- Enter a justification for your subscription request.
- Choose Subscribe.

- Switch to the data publisher role to approve the subscription request, then back to data subscriber after choosing Approve.

- Select the Glue_subscribe_project and choose Subscribed Assets. Verify that the Market Sales Table is added to your environment.

- Navigate to the Amazon Athena query editor using the link in the project’s home page.
- Choose OPEN AMAZON ATHENA.

- You will now be automatically routed to the Athena console, make sure that the Amazon DataZone Environment is set to glue_subscribe_environment.
- For Database, select glue_subscribe_environment_sub_db.
- You should see the
mkt_sls_tablein the Tables list. Preview the table by choosing the three-dot menu next to the table name and selecting Preview Table

- Review the table preview results. You will be able to see all the sales related data from the
mkt_sls_table


Subscribe to the Redshift table
- Stay signed in to the Amazon DataZone management console as the data subscriber, Choose Select project from the top navigation pane and select the Redshift_Subscribe_project.
- Search for Sales Table in the search bar, and select the Sales Table.
- In the Subscribe pop-up window, provide the following information:
- Project: Enter the name of the project that you want to subscribe to the asset. By default this will be Redshift_Subscribe_Project.
- Enter a justification for your subscription request.
- Choose Subscribe.
- Switch back to the data publisher who is the producer of the Market Sales Table choose Approve.

- After the subscription request is approved, switch back to data subscriber.
- Select the Redshift_subscribe_project and choose Subscribed Assets. After the Sales Table is added to your environment, you can query the data in the table.
- Select the Amazon Redshift link in the right side panel of the project home page and navigate to the Amazon Redshift query editor.
- Select Open Amazon Redshift and the Redshift query editor v2 will open in a new tab.

- In the query editor, right-click your Amazon DataZone environment’s Amazon Redshift cluster and select Create a connection.
- Select Temporary credentials using your IAM identity for authentication.
- If that authentication method isn’t available, open Account settings by choosing the gear icon in the bottom left corner, choose Authenticate with IAM credentials and choose Save.

- If that authentication method isn’t available, open Account settings by choosing the gear icon in the bottom left corner, choose Authenticate with IAM credentials and choose Save.
- Enter the name of the Amazon DataZone environment’s database to create the connection.
- Choose Create connection.
- You can now view the Redshift table
rs_sls_tblin the datazone_env_redshift_subscribe_environment. - Execute the following query to make sure the data is accessible


You will be able to preview the rs_sls_tbl which will show the sale data from the table.
Clean up
To avoid unnecessary future charges, follow these steps:
- Delete the Amazon DataZone project if you created it as part of this post.
- Delete the Amazon DataZone domain if you created it as part of this post.
- Delete the Redshift clusters and the redshift secrets in both the producer and consumer accounts if you created them as part of the post.
Summary
Organizations often face significant challenges when trying to share data products across multiple AWS accounts. These challenges stem from the complexity of configuring proper cross-account access permissions and roles while maintaining robust data governance and security controls.
You can use the solution described in the post to publish and consume data across AWS accounts and make sure that reliable access and consistent data governance is in place. By combining the power of AWS Glue and Amazon Redshift, you can unlock valuable insights and accelerate your data-driven decision-making processes.
In this post, you followed a step-by-step guide to set up cross-account data sharing using Amazon DataZone domain association. You learned how to publish data assets from a producer account. You also learned how to subscribe to and query the published assets from a consumer account. You can optionally use AWS Lake Formation access monitoring to view permissions and data access activities. AWS Lake Formation uses AWS CloudTrail for historical analysis and CloudTrail retains logs for 90 days by default.
Now that you’re familiar with the elements involved in cross-account data sharing using Amazon DataZone and your choice of analytical tool, you’re ready to try it with multiple accounts.
About the Authors
 Arun Pradeep Selvaraj is a Senior Solutions Architect at AWS. Arun is passionate about working with his customers and stakeholders on digital transformations and innovation in the cloud while continuing to learn, build and reinvent. He is creative, fast-paced, deeply customer-obsessed, and uses the working backwards process to build modern architectures to help customers solve their unique challenges. Connect with him on LinkedIn.
 Piyush Mattoo is a Senior Solution Architect for the Financial Services Data Provider segment at Amazon Web Services. He’s a software technology leader with over a decade of experience building scalable and distributed software systems to enable business value through the use of technology. He has an educational background in Computer Science with a master’s degree in computer and information science from University of Massachusetts. He is based out of Southern California and current interests include camping and nature walks.
 Mani Yamaraja is a Senior Customer Solutions Manager for Financial Services Data Provider segment at Amazon Web Services. He has over a decade long experience working with financial services customers enabling their digital transformation journey. Mani adopts a customer centric approach and provides technology solutions working backwards from customer’s business goals. He is passionate about the financial services industry and helps the customers accelerate their cloud based transformation using the proven mechanisms of AWS.
New 512GB Unified Memory Apple Mac Studio is the Local AI Play
Post Syndicated from Cliff Robinson original https://www.servethehome.com/new-512gb-unified-memory-apple-mac-studio-is-the-local-ai-play/
The Apple Mac Studio with 512GB of unified memory and the M3 Ultra is going to be the AI tool folks salivate over
The post New 512GB Unified Memory Apple Mac Studio is the Local AI Play appeared first on ServeTheHome.
Xen 4.20 released
Post Syndicated from jzb original https://lwn.net/Articles/1013104/
The Xen Project has announced
the release of Xen 4.20. This release adds support for
AMD Zen 5 CPUs, improved compliance with the MISRA C standard,
work on PCI-passthrough on Arm, and more. Xen 4.20 also removes
support for Xeon
Phi CPUs, which were discontinued
in 2018. See the feature
list and release
notes for more information.
Thunderbird Desktop 136.0 released
Post Syndicated from jzb original https://lwn.net/Articles/1013098/
Version
136.0 of the Thunderbird Desktop mail client has been
released. The release includes a quick toggle for adapting messages to
dark mode, and a new “Appearance” setting to control message threading
and sorting order globally, as well as a number of bug fixes. See the
security
advisory for a full list of security vulnerabilities addressed in
Thunderbird 136.0.
Linux from Scratch version 12.3 released
Post Syndicated from jzb original https://lwn.net/Articles/1013096/
Version
12.3 of Linux From
Scratch (LFS) has been released, along with Beyond Linux
From Scratch (BLFS) 12.3. LFS provides step-by-step instructions
on building a customized Linux system entirely from source, and BLFS
helps to extend an LFS installation into a more usable system. Notable
changes in this release include toolchain updates to GNU Binutils
2.44, GNU C Library (glibc) 2.41, and Linux 6.13.2. The Changelog
has a full list of changes since the previous stable release.
Comic for 2025.03.05 – The First Cojoined Twins
Post Syndicated from Explosm.net original https://explosm.net/comics/the-first-cojoined-twins
New Cyanide and Happiness Comic
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1013063/
Security updates have been issued by Debian (libreoffice), Fedora (exim and fscrypt), Red Hat (kernel), Slackware (mozilla), SUSE (docker, firefox, and podman), and Ubuntu (linux, linux-lowlatency, linux-lowlatency-hwe-5.15, linux, linux-lowlatency, linux-lowlatency-hwe-6.8, linux, linux-oem-6.11, linux-aws, linux-aws-6.8, linux-oracle, linux-oracle-6.8, linux-raspi, linux-aws, linux-gcp, linux-hwe-6.11, linux-oracle, linux-raspi, linux-realtime, linux-aws, linux-gkeop, linux-ibm, linux-intel-iotg, linux-intel-iotg-5.15, linux-oracle, linux-oracle-5.15, linux-raspi, and linux-gcp, linux-gcp-6.8, linux-gke, linux-gkeop).
Inside the Take Command Summit 2025 Agenda: What’s in Store for This Year’s Event?
Post Syndicated from Rapid7 original https://blog.rapid7.com/2025/03/05/inside-the-take-command-summit-2025-agenda-whats-in-store-for-this-years-event/
The cybersecurity landscape is shifting fast—ransomware is evolving, AI is reshaping security operations, and regulations are becoming more complex than ever. Security teams are under pressure to outpace adversaries, manage risk, and defend against sophisticated threats.
That’s why Take Command 2025 is built to deliver the most relevant, actionable insights security leaders need to navigate these challenges. This full-day virtual event brings together top security minds—from Rapid7’s experts to industry analysts and frontline defenders—covering the strategies, tools, and intelligence to help you take command of your attack surface.
A pre-recorded message from Rapid7 CEO Corey Thomas is already live on our event site, providing an inside look at what you can expect from Take Command 2025, and how our global summit will help security teams stay ahead of emerging threats.See the full list of speakers and watch Corey Thomas’s message on the Take Command 2025 registration page.
A Glimpse Into This Year’s Key Themes
This year’s agenda is packed with deep-dive discussions, real-world case studies, and expert insights on the most pressing security topics today. Here are just a few of the key focus areas you can expect at Take Command 2025:
Understanding the Evolving Threat Landscape
Cybercriminals are always one step ahead—until you learn to think like they do. This panel discussion, led by Raj Samani, Rapid7’s Chief Scientist, will explore the latest attack methodologies, emerging ransomware tactics, and evolving adversary behaviors.
Raj will be joined by Trent Teyema, Founder and President of CSG Strategies, a former FBI Special Agent (SES retired), as they analyze real-world attacker techniques and share how security teams can leverage threat intelligence to anticipate and disrupt threats before they escalate.
Session: Inside the Mind of an Attacker: Navigating the Threat Horizon
AI & Cloud Security: Opportunities and Challenges
AI is transforming cybersecurity, but how can organizations implement it responsibly and effectively? Take Command 2025 will examine:
- The future of AI-powered security operations—what’s hype vs. reality?
- How SOC and MDR teams are leveraging AI to improve detection and response
- Cloud security challenges and why cloud detection & response (CDR) is becoming a critical SOC capability
Thom Langford, Regional CTO at Rapid7, will host this discussion, featuring Ted Harrington, Executive Partner at ISE (the Company of Ethical Hackers). Together, they will explore how AI-powered, Zero Trust-based security models are changing how organizations approach risk and resilience, and what the next era of cybersecurity defense will look like in our ‘From Zero to Hero: Building the Perfect Defense’ session.
Exposure Management & Red Teaming: Proactive Security in Action
Security teams can’t afford to wait for attacks to happen. Implementing proactive security strategies are critical. Take Command 2025 will explore:
- How red teaming is evolving to match today’s complex threat landscape
- Real-world lessons from leading vulnerability management programs
- Why organizations are shifting from traditional vulnerability scanning to proactive exposure management
Industry analyst Tyler Shields (ESG) and offensive security consultant Will Hunt (In.Security) will lead key discussions, sharing practical insights on prioritizing risk, testing defenses, and staying ahead of attackers.
Navigating Regulatory & Compliance Complexity
With NIS2, DORA, SEC regulations, and other global mandates becoming more prescriptive, CISOs need to stay ahead of compliance changes—but these evolving policies also present an opportunity to strengthen security programs.
Sessions will focus on:
- How regulatory frameworks are reshaping security practices across industries
- Key compliance challenges for global organizations and strategies for staying ahead
- The intersection of security, policy, and business risk—how to turn compliance into a competitive advantage
Sabeen Malik, Rapid7’s VP of Global Government Affairs & Public Policy, will help demystify cyber regulations, compliance challenges, and evolving data residency concerns in ‘From Chaos to Compliant: Demystifying Cyber Regulations’.
More to Come: A Full Day of Cybersecurity Insights
This is just a preview of the cutting-edge discussions, expert panels, and strategic deep-dives planned for Take Command 2025. Across the day, you’ll also hear from Rapid7’s own SOC experts, product leaders, and security researchers, who will provide real-world insights into:
- What’s next for AI-driven security operations
- How real-world attack simulations are changing security strategy
- Inside the SOC: Expert stories from frontline threat hunters
Whether you’re a practitioner, security leader, or researcher, this event is designed to give you the insights and strategies needed to strengthen your security posture in 2025 and beyond.
Register Now to Take Command
Take Command 2025 is a free, global, virtual event happening on April 9. Don’t miss your chance to hear from security leaders and experts on the biggest challenges shaping the industry.
Casualties of the West Point Class of 42 -vol 3
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=JbpL2rZMsSo
CISA Identifies Five New Vulnerabilities Currently Being Exploited
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/cisa-identifies-five-new-vulnerabilities-currently-being-exploited.html
Of the five, one is a Windows vulnerability, another is a Cisco vulnerability. We don’t have any details about who is exploiting them, or how.
Критика на граматичния разум
Post Syndicated from original https://www.toest.bg/kritika-na-ghramatichniya-razum/

Ще ме последвате ли в дълбокото? Обещавам да не се удавим. Нека се гмурнем заедно в академичната платформа „Български езикови ресурси онлайн“ (БЕРОН) и да проверим някои думи, които ежедневно употребяваме.
Започваме например с аз. Непосредствено под думата прочитаме: „клас съществително местоимение“. „Клас“ ще рече част на речта¹ и това можем да го асимилираме, но „съществително местоимение“ е… да речем, озадачаващо. Сега това съществително ли е, или местоимение? Сигурно е местоимение, което е съществително. А дали пък не е съществително, което е местоимение? Чакайте, чакайте,
много добре си спомням от училище, че аз е лично местоимение. И това ли вече не е така?
Ако скролнем настрани, ще стигнем до следната информация: „С формите на съществителното местоимение аз се означава авторът на текста – т.е. говорещият (пишещият). По традиция аз се определя като лично местоимение за първо лице“. От този текст разбираме, първо, че аз вероятно се числи към класа на съществителните (имена)², а местоимението ще да е един от подкласовете, и второ, това е добре познатото ни старо лично местоимение, но с нова категоризация.
На какво се дължи тази промяна в класификацията на граматичните класове думи? Както разбираме от публикации в научната периодика, предстои да бъде издадена нова академична граматика на българския език, която ще бъде и нормативна³. Отдавна е време за това – предишната е от миналия век (1982 – 1983).
Засега информацията за бъдещата граматика, изготвяна от учени от Института за български език (ИБЕ) на БАН, е доста ограничена, но все пак знаем, че в нея ще бъде представено нещо принципно различно.
Нова класификация на класовете думи (частите на речта)
В новите мнения, възгледи, концепции, модели и т.н. в науката сами по себе си няма нищо лошо – напротив, така се развива и обогатява човешкото познание за света, който ни заобикаля. Когато на научното поле се срещнат различни мнения и те са солидно аргументирани, обикновено надделяват тези, които по-добре концептуализират (ех, каква завъртяна дума, простете, но тя ми дойде в ума) действителността и ни помагат да я опознаем по-добре, а после и да боравим с овладяната материя.
Да видим какво ни е известно до момента за новата граматична класификация и как/дали това ще ни помогне да си обясняваме по-добре езика и да си служим с него. Ще трябва да тръгнем от съществуващата, традиционната, според която
класовете думи са 10 на брой: съществително име, прилагателно име, числително име, местоимение, глагол (вкл. причастията), наречие, предлог, съюз, частица, междуметие.
Тя стъпва на два основни критерия – семантичен и граматичен, тоест всеки от горните класове обединява думи, които имат нещо най-общо в значението си, а също така и общи граматични категории. Прилагателните имена например са обединени от това, че означават признаци на лица и предмети, а също така имат род, число, определеност/неопределеност (могат да се членуват), някои имат и степен. Глаголите назовават действие или състояние и имат лице, число, време, залог и т.н.
Новата класификация игнорира семантичния критерий – тоест най-общото в значението няма значение – и се основава изцяло на формалния подход при разпределянето на думите по класове:
Този подход е базиран на стриктното разграничение между форма и семантика чрез прилагането на строги морфо-синтактични критерии.⁴
Засега имаме по-пълна информация само за класа на прилагателните имена. Ето кои подкласове ще включва той:
1. Прилагателни в собствен смисъл (същински прилагателни).
Това са старите наши познайници – думи като добър, жълт, градски, тоест прилагателните имена, каквито ги знаем и си ги представяме в момента.
2. Прилагателни местоимения.
Новото попълнение в класа на прилагателните имена включва няколко вида от познатите ни местоимения:
а) показателни (този, онзи);
б) притежателни (мой/ми, твой/ти, негов/му);
в) възвратни притежателни (свой);
г) въпросителни (кой, какъв);
д) относителни (който, какъвто);
е) неопределителни (някой, някакъв, нечий);
ж) отрицателни (никой, никакъв, ничий);
з) обобщителни (всеки, всякакъв)⁵.
Всъщност това са всички местоимения с изключение на личните (аз, ти) и възвратното лично (себе си).
Основанието да се причислят тези думи към прилагателните имена е, че повечето от тях могат да се променят по род и число и да се членуват, например мой (моя, моят), моя(та), мое(то), мои(те). Тук трябва да направим важното уточнение, че кой, който, някой, никой и всеки са прилагателни в случаи като Всеки приятел ще се зарадва на успеха ти (определение към приятел), но ако са употребени самостоятелно, ще попаднат в големия клас на съществителните имена: Всеки ще се зарадва на успеха ти (в ролята на подлог). И това не е всичко, има случаи, в които думата ще е подлог, обаче вероятно ще трябва да я таксуваме като прилагателно, защото се променя по род: Всяка от вас трябва да внимава (когато говорещият се обръща към жени).
3. Прилагателни числителни.
Познатите ни редни числителни имена (първи, втори, трети) действително много приличат на прилагателните имена по своите граматични характеристики – изменят се по род и число и се членуват. Това се отбелязва от немалко български езиковеди и няма как да се пренебрегне. Редно е също да признаем, че със сегашните числителни бройни (едно, две, три) в момента ги обединява най-вече значението. Все пак имат поне една обща граматична категория – определеност/неопределеност (членуват се).
4. Глаголни прилагателни.
Също както при подкласа на местоименията ще трябва да заострим вниманието си, защото пак ще правим разграничения. Глаголните прилагателни са всъщност част от причастията, които според традиционната класификация представляват глаголни форми. И действително, те са образувани от глаголи. Да си припомним видовете причастия:
а) сегашно деятелно – търсещ;
б) минало свършено деятелно – търсил, потърсил;
в) минало несвършено деятелно – търсел;
г) минало страдателно – търсен;
д) деепричастие – търсейки.
Причастията, които се изменят по род и число и се членуват (а, б, г), вече ще бъдат глаголни прилагателни – търсещ(ият) човек, търсеща(та) жена; потърсила(та) правата си майка, потърсили(те) правата си хора; търсена(та) стока, търсени(те) професии.
Тези обаче, с които се образуват форми за различни глаголни времена и наклонения, ще си останат причастия:
Майката търсела правата си. (преизказна форма – минало несвършено деятелно причастие)
Майката е търсила правата си. (форма за минало неопределено време, включваща минало свършено деятелно причастие)
Тази стока сега е търсена на пазара. (форма за страдателен залог, включваща минало страдателно причастие)
И така, пак ще трябва да разграничаваме едни и същи думи и да ги причисляваме ту към глаголните прилагателни (търсена стока) – ту пък към причастията, тоест към системата на глагола (стоката е търсена). Това се отнася за миналото свършено деятелно причастие и миналото страдателно причастие.
Под секрет ще ви кажа, че и аз започнах да се обърквам – представям си какви усилия трябва да положи един нефилолог, за да проследи тези трансформации, отношения и разграничения. Завършвайки с информацията за глаголните прилагателни, нека се простим.
Сбогом, сегашно деятелно причастие, сбогом, деепричастие! Ще се видим в някой следващ живот може би.
Съдбата на думите, които сега категоризираме като деепричастия, в момента поне на мен не ми е ясна, но предполагам, че ще бъдат отнесени към наречията.
5. Неизменяеми прилагателни.
Само ще маркирам последния подклас прилагателни имена, тъй като той е обект на много дискусии в езиковедската литература. Освен думи като инат, сербез, късметлия, причислявани обикновено към него, все повече набъбва броят на лексемите от западноевропейските езици, особено от английския: супер, екстра, денс, макси и др.
Други граматични класификации
Предлаганото от учените от ИБЕ прекатегоризиране на думите, както можем да предположим, не е изолирано явление в българското езикознание и е редно да го поставим в контекст. В по-ново време може да се посочат класификациите на Юрий Маслов (1981) и Станьо Георгиев (1991). Подробен преглед на концепциите прави Константин Куцаров в своята дисертация „Българските лексемни класове и учението на частите на речта“ (2019)6. Стъпвайки на три критерия – лексико-семантичен, морфологичен и синтактичен, – ученият аргументира обособяването на 12 лексемни класа. Като цяло местоименията не представляват отделен клас, единствено личните (аз, ти, той) са обособени в „дискурсив“. Самостоятелен клас образуват причастията, с изключение на деепричастията, и „детерминативите“, които в момента се разглеждат в синтаксиса като вметнати думи (впрочем, наистина, например). В края на автореферата на дисертацията си Куцаров с основание отбелязва:
… няма класификационен модел, който да не бъде уязвим, тъй като изначално е обременен от субективността на изследователските тези. Това научно съчинение предлага само една от възможните гледни точки по проблема.
Напълно подкрепям виждането на проф. Куцаров. Когато предлагаш нещо принципно ново, отклоняващо се от традицията, ревизиращо традицията и оспорващо традицията, е редно да имаш съзнанието, че това е „само една от възможните гледни точки“, и да не я налагаш като истина от последна инстанция.
Като всеки езиков модел, и сегашната класификация, каквато я знаем от десетилетия, не е съвършена. В никакъв случай не я издигам в култ и не смятам, че е дадена веднъж завинаги и не бива да се търсят по-добри модели. Мисля обаче, че няма как изведнъж да се появи класификация, която веднага да бъде приета от научните среди и обществото и безпроблемно да стане нормативна.
Новата граматична класификация на ИБЕ, отразена в БЕРОН
Може все още да сме в неведение за цялостната концепция на учените от ИБЕ, но тя вече тихомълком е прокарана в БЕРОН, който, по техните думи, е „мощен инструмент за грамотност на всеки българин с достъп до интернет“, „особено ценен за сферата на образованието и най-вече за обучението по български език във и извън България“. Освен че, както споменахме, кой и някой например фигурират като съществителни местоимения и прилагателни местоимения, прекласифицирани са думи като безброй (вече не е наречие, а числително име), колко и толкова (не са местоимения за количество, а са числителни имена (толкова приятели) и наречия (толкова те обичам). Учудване у мен предизвика следният факт: много и малко също са числителни имена и наречия, но само малко може да бъде и съществително име. Защо тази битност е отказана на много? Причастията пък все още са в сегашния си вид и при съответните глаголи са представени всички причастни форми, което ме навежда на мисълта, че прекласифицирането не е доведено докрай.
Дори и в този вид обаче имаме достатъчно основания да се запитаме:
кому е нужно всичко това и каква е ползата от него?
Знаем откъслечни неща за новите класове думи – и то ние, специалистите, които сме се натъкнали на промените, – обаче неизвестни и объркващи дори и филолозите термини, като съществително местоимение, вече фигурират в БЕРОН. Къде е цялостно разработената нова теория за класовете думи? Не трябваше ли тя да бъде публикувана и дискутирана и едва след това евентуално да бъде официализирана и отразена в БЕРОН – една платформа, която, както е декларирано, трябва да служи на „всеки българин“, на цялото общество. Да напомня на колегите от ИБЕ, че същото това общество в огромната си част се състои от нефилолози. Но дори и филолозите – отново в огромната си част – не подозират за намеренията за граматични нововъведения от такъв мащаб.
Учудващо е, че учените от ИБЕ имат смелостта – и това не е точната дума, която си заслужава да употребя – направо да наложат като нормативна една граматична класификация, за която малко специалисти знаят. Да не говорим че въпросната класификация изобщо не е проверена в практиката.
Нека да припомня какво пише в академичната граматика от 1982 – 1983 г.:
С оглед на основната си цел граматиката е съставена с помощта на традиционна в основата си концепция, методология и терминология. По принцип съставителите се опират на утвърдени в българската граматична литература постановки и се избягват подчертано дискусионни положения.7
Питам се защо учените от ИБЕ отстъпват от разумния подход на своите именити предшественици и на какво почива тяхната увереност, че ще поднесат концепция, която най-малкото няма да провокира съществени възражения.
Основният въпрос според мен обаче е какви практически ползи ще ни донесе новата класификация.
По-добре ли ще си обясняваме и ще подреждаме езиковата действителност в съзнанието си? Ще доведе ли това до по-бързо и трайно усвояване на граматичните, правописните и пунктуационните норми? Или напротив – ще прахосаме ценна енергия в прекрояването, преподреждането и новото съшиване на езиковата материя. И междувременно може да се изгубим някъде там, между съществителните местоимения, глаголните прилагателни и думите, които могат да бъдат наречия, числителни и съществителни.
С непрозрачната си езикова политика ИБЕ отдавна е длъжник на българското общество. Още повече Институтът дължи отговори сега, преди някой ден да сме осъмнали под диктата на нова нормативна граматика.
Или по-лошо – с нова нормативна граматика, с която няма да искаме да се съобразяваме.
Изложеното в статията мнение е лично мое и не ангажирам никого с него.
1 Терминът части на речта в българското езикознание вече се измества от (граматични) класове думи/лексеми. Намирам новия термин за коректен.
2 В съществителното местоимение първата дума може да се възприеме и като прилагателно име. Всъщност терминът трябва да се разбира като „клас съществително име, подклас местоимение“.
3 Станчева, Р., Томов, М. Класът на прилагателните имена в нормативната граматика на българския език – формален подход. – Български език, 2023, Приложение, с. 73 – 91.
4 Пак там, с. 73.
5 Примерите в скобите не изчерпват всички местоимения от съответния вид.
6 Дисертацията е публикувана като монография със същото заглавие през 2022 г. от издателство „Колибри“.
7 Граматика на съвременния български книжовен език. Т. 1. Фонетика. София: Издателство на БАН, 1982, с. 7.
Езикът може да е вкусен и извън блюдото – онзи, българският език, на който говорим от малки и на който около 24 май се кълнем в обич. А той в същността си е средство за общуване и за да ни служи добре, непрекъснато се променя. Да го погледнем в неговата динамика и да се опитаме да разберем какво става и защо, кои са движещите механизми и как те са свързани с обществените процеси. И тъй като задачата не е лека, ще го правим постепенно – на порции.
Title Launch Observability at Netflix Scale
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/title-launch-observability-at-netflix-scale-8efe69ebd653
Part 3: System Strategies and Architecture
By: Varun Khaitan
With special thanks to my stunning colleagues: Mallika Rao, Esmir Mesic, Hugo Marques
This blog post is a continuation of Part 2, where we cleared the ambiguity around title launch observability at Netflix. In this installment, we will explore the strategies, tools, and methodologies that were employed to achieve comprehensive title observability at scale.
Defining the observability endpoint
To create a comprehensive solution, we decided to introduce observability endpoints first. Each microservice involved in our Personalization stack that integrated with our observability solution had to introduce a new “Title Health” endpoint. Our goal was for each new endpoint to adhere to a few principles:
- Accurate reflection of production behavior
- Standardization across all endpoints
- Answering the Insight Triad: “Healthy” or not, why not and how to fix it.
Accurately Reflecting Production Behavior
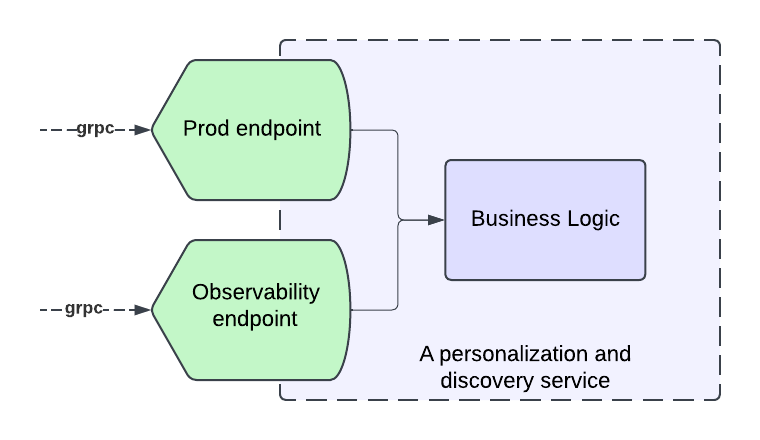
A key part of our solution is insights into production behavior, which necessitates our requests to the endpoint result in traffic to the real service functions that mimics the same pathways the traffic would take if it came from the usual callers.
In order to allow for this mimicking, many systems implement an “event” handling, where they convert our request into a call to the real service with properties enabled to log when titles are filtered out of their response and why. Building services that adhere to software best practices, such as Object-Oriented Programming (OOP), the SOLID principles, and modularization, is crucial to have success at this stage. Without these practices, service endpoints may become tightly coupled to business logic, making it challenging and costly to add a new endpoint that seamlessly integrates with the observability solution while following the same production logic.
Standardization
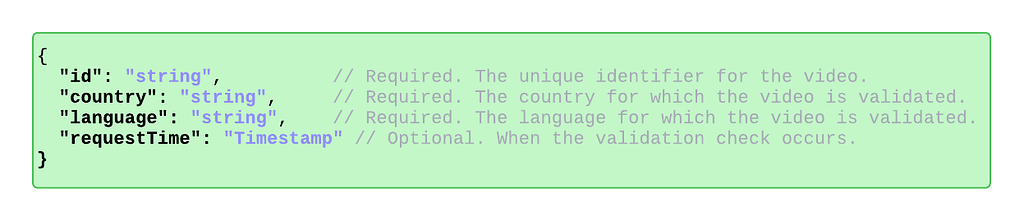
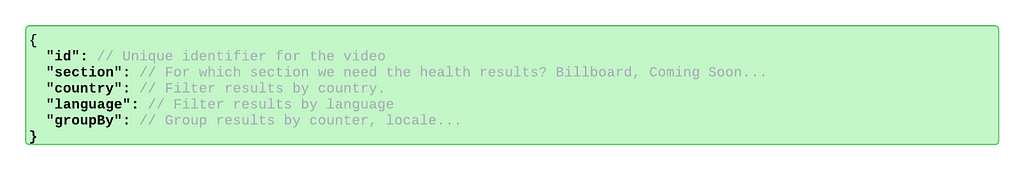
To standardize communication between our observability service and the personalization stack’s observability endpoints, we’ve developed a stable proto request/response format. This centralized format, defined and maintained by our team, ensures all endpoints adhere to a consistent protocol. As a result, requests are uniformly handled, and responses are processed cohesively. This standardization enhances adoption within the personalization stack, simplifies the system, and improves understanding and debuggability for engineers.
The Insight Triad API
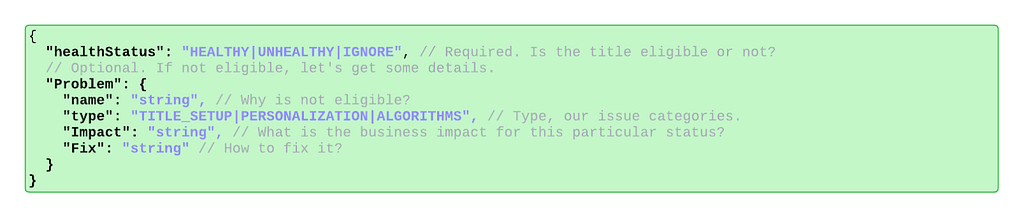
To efficiently understand the health of a title and triage issues quickly, all implementations of the observability endpoint must answer: is the title eligible for this phase of promotion, if not — why is it not eligible, and what can be done to fix any problems.
The end-users of this observability system are Launch Managers, whose job it is to ensure smooth title launches. As such, they must be able to quickly see whether there is a problem, what the problem is, and how to solve it. Teams implementing the endpoint must provide as much information as possible so that a non-engineer (Launch Manager) can understand the root cause of the issue and fix any title setup issues as they arise. They must also provide enough information for partner engineers to identify the problem with the underlying service in cases of system-level issues.
These requirements are captured in the following protobuf object that defines the endpoint response.
High level architecture
We’ve distilled our comprehensive solution into the following key steps, capturing the essence of our approach:
- Establish observability endpoints across all services within our Personalization and Discovery Stack.
- Implement proactive monitoring for each of these endpoints.
- Track real-time title impressions from the Netflix UI.
- Store the data in an optimized, highly distributed datastore.
- Offer easy-to-integrate APIs for our dashboard, enabling stakeholders to track specific titles effectively.
- “Time Travel” to validate ahead of time.
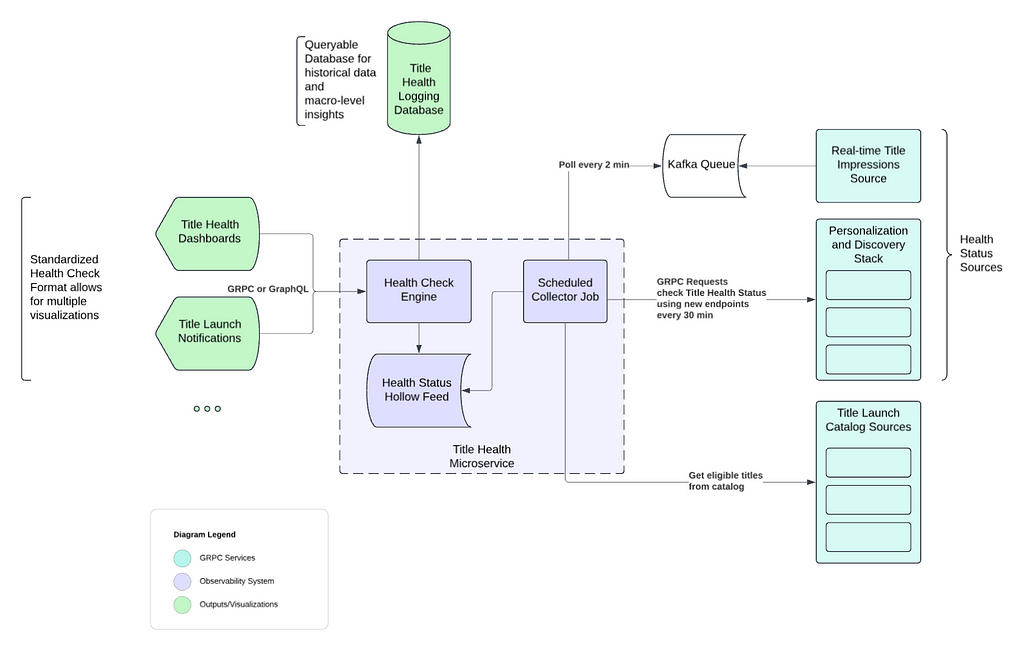
In the following sections, we will explore each of these concepts and components as illustrated in the diagram above.
Key Features
Proactive monitoring through scheduled collectors jobs
Our Title Health microservice runs a scheduled collector job every 30 minutes for most of our personalization stack.
For each Netflix row we support (such as Trending Now, Coming Soon, etc.), there is a dedicated collector. These collectors retrieve the relevant list of titles from our catalog that qualify for a specific row by interfacing with our catalog services. These services are informed about the expected subset of titles for each row, for which we are assessing title health.
Once a collector retrieves its list of candidate titles, it orchestrates batched calls to assigned row services using the above standardized schema to retrieve all the relevant health information of the titles. Additionally, some collectors will instead poll our kafka queue for impressions data.
Real-time Title Impressions and Kafka Queue
In addition to evaluating title health via our personalization stack services, we also keep an eye on how our recommendation algorithms treat titles by reviewing impressions data. It’s essential that our algorithms treat all titles equitably, for each one has limitless potential.
This data is processed from a real-time impressions stream into a Kafka queue, which our title health system regularly polls. Specialized collectors access the Kafka queue every two minutes to retrieve impressions data. This data is then aggregated in minute(s) intervals, calculating the number of impressions titles receive in near-real-time, and presented as an additional health status indicator for stakeholders.
Data storage and distribution through Hollow Feeds
Netflix Hollow is an Open Source java library and toolset for disseminating in-memory datasets from a single producer to many consumers for high performance read-only access. Given the shape of our data, hollow feeds are an excellent strategy to distribute the data across our service boxes.
Once collectors gather health data from partner services in the personalization stack or from our impressions stream, this data is stored in a dedicated Hollow feed for each collector. Hollow offers numerous features that help us monitor the overall health of a Netflix row, including ensuring there are no large-scale issues across a feed publish. It also allows us to track the history of each title by maintaining a per-title data history, calculate differences between previous and current data versions, and roll back to earlier versions if a problematic data change is detected.
Observability Dashboard using Health Check Engine
We maintain several dashboards that utilize our title health service to present the status of titles to stakeholders. These user interfaces access an endpoint in our service, enabling them to request the current status of a title across all supported rows. This endpoint efficiently reads from all available Hollow Feeds to obtain the current status, thanks to Hollow’s in-memory capabilities. The results are returned in a standardized format, ensuring easy support for future UIs.
Additionally, we have other endpoints that can summarize the health of a title across subsets of sections to highlight specific member experiences.
Time Traveling: Catching before launch
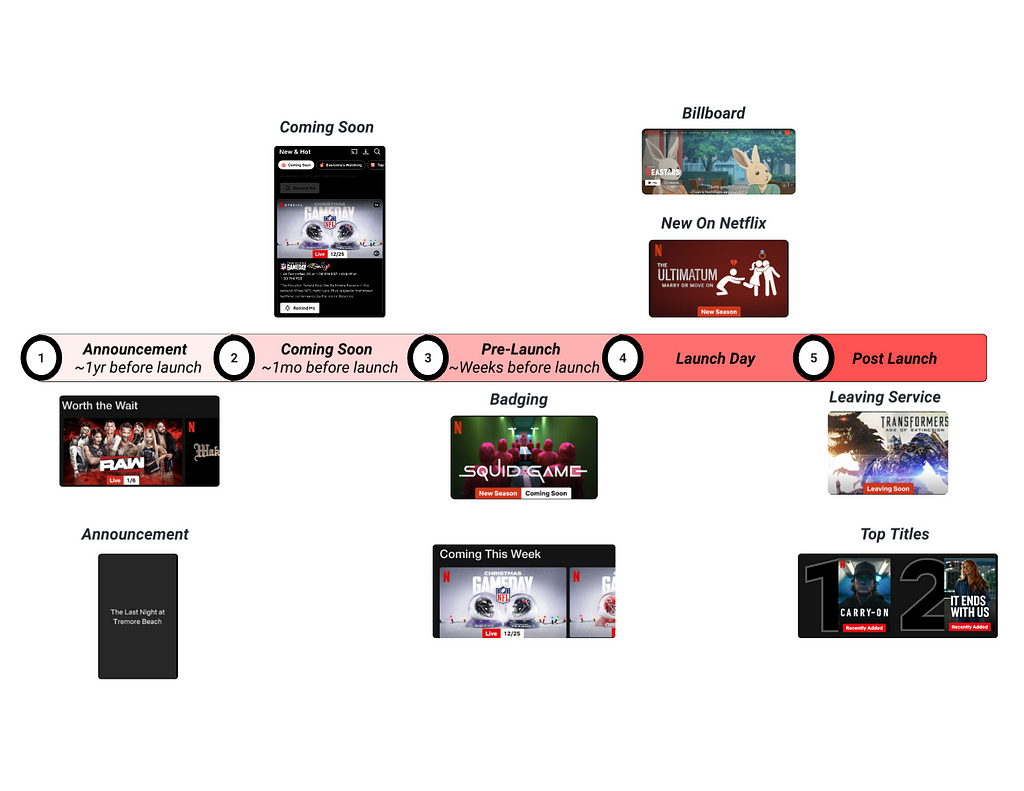
Titles launching at Netflix go through several phases of pre-promotion before ultimately launching on our platform. For each of these phases, the first several hours of promotion are critical for the reach and effective personalization of a title, especially once the title has launched. Thus, to prevent issues as titles go through the launch lifecycle, our observability system needs to be capable of simulating traffic ahead of time so that relevant teams can catch and fix issues before they impact members. We call this capability “Time Travel”.
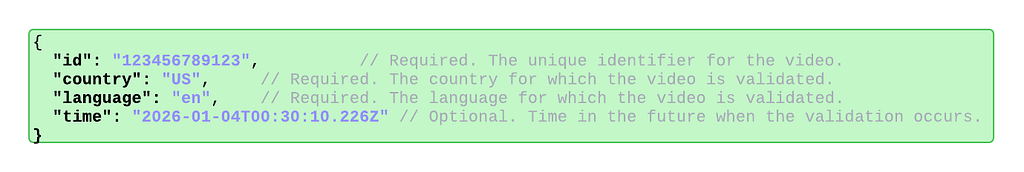
Many of the metadata and assets involved in title setup have specific timelines for when they become available to members. To determine if a title will be viewable at the start of an experience, we must simulate a request to a partner service as if it were from a future time when those specific metadata or assets are available. This is achieved by including a future timestamp in our request to the observability endpoint, corresponding to when the title is expected to appear for a given experience. The endpoint then communicates with any further downstream services using the context of that future timestamp.
Conclusion
Throughout this series, we’ve explored the journey of enhancing title launch observability at Netflix. In Part 1, we identified the challenges of managing vast content launches and the need for scalable solutions to ensure each title’s success. Part 2 highlighted the strategic approach to navigating ambiguity, introducing “Title Health” as a framework to align teams and prioritize core issues. In this final part, we detailed the sophisticated system strategies and architecture, including observability endpoints, proactive monitoring, and “Time Travel” capabilities; all designed to ensure a thrilling viewing experience.
By investing in these innovative solutions, we enhance the discoverability and success of each title, fostering trust with content creators and partners. This journey not only bolsters our operational capabilities but also lays the groundwork for future innovations, ensuring that every story reaches its intended audience and that every member enjoys their favorite titles on Netflix.
Thank you for joining us on this exploration, and stay tuned for more insights and innovations as we continue to entertain the world.

Title Launch Observability at Netflix Scale was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
The Most Trusted Man in America
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=BzrqHaUi7Uc
Water Damage
Post Syndicated from xkcd.com original https://xkcd.com/3059/
The Missouri Compromise
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=Mh2F_ShjekQ
Architecting for seamless on-premises connectivity with AWS Outposts servers
Post Syndicated from aostan original https://aws.amazon.com/blogs/compute/architecting-for-seamless-on-premises-connectivity-with-aws-outposts-servers/
This post is written by Mark Nguyen, Principal Solutions Architect, AWS and Ryan Fillis, Solutions Architect, AWS.
AWS Outposts brings native AWS services, infrastructure, and operating models to virtually any data center, co-location space, or on-premises facility. Deploying Outposts servers in your environment necessitates additional considerations regarding local network connectivity and Amazon Elastic Compute Cloud (Amazon EC2) instance networking. This post demonstrates the scalability of Outposts servers through automation and the deployment of Amazon EC2 network interfaces. This reduces the number of manual steps required to configure an Outposts server.
This post details physically connecting your servers to your Local Area Network (LAN) and the networking options available for EC2 instances running on Outposts. We cover the physical cabling options, virtual networking components such as VPCs and subnets, and walkthrough an example setup for an EC2 instance with a user-data script to route traffic locally over your on-premises network.
This post assumes that you have some familiarity with Outposts servers. If you would like a general refresher, observe What is AWS Outposts. For more information about how to provision your Outposts server, see Installing an AWS Outposts server.
Basic Amazon EC2 networking using a single interface
When launching an EC2 instance on an Outposts server a single interface is created for network connectivity. This default setting, depicted in the following diagram, is the most direct method for your instance to communicate externally.

Figure 1: Simple network connectivity on an Outposts server
When deploying an EC2 instance to an Outposts server, there are certain differences in using the default Elastic Network Interface (ENI) as compared to deploying in an AWS Region. Understanding these differences is critical before modifying the network configuration, which you do in the next step.
ENI differentiators between Outposts servers and the Region:
- Primary interface: The primary interface is an ENI. This ENI is associated to a subnet within a VPC. This VPC is extended from the Region to the Outposts server.
- IP address configuration: The primary network interface within the guest operating system (OS) of the EC2 instance must be configured to obtain an IP address through DHCP. The assigned IP address is from the IP address range of the VPC subnet associated with the Outposts server.
- Security group: A security group is associated with the ENI. This security group falls within the VPC that is extended from the Region. The user must apply appropriate access control rules to permit access to the EC2 instance. You may reuse security groups that already exist within the VPC.
- Outbound traffic: By default, an EC2 instance uses its ENI to direct outbound traffic toward the VPC subnet. Traffic flows according to the routing table associated with the Outposts server’s VPC subnet.
- Inbound traffic: If you’re only using an ENI, then traffic destined to EC2 instances on Outposts servers must traverse through the service link. In the preceding diagram, the user communicates with the EC2 instance over the internet. Traffic from the internet reaches the Region through the Internet Gateway of the VPC. Then, the VPC forwards the traffic to the appropriate subnet of the Outposts server (through the service link) and reaches the EC2 instance. The user must configure the necessary VPC components (Internet Gateway and associated routing table entries) for internet connectivity.
- Local network connectivity: There is no local network connectivity using the ENI. For local network connectivity, see the next section where we discuss the Outposts server Local Network Interface (LNI).
Local network connectivity for EC2 instances
Outposts servers allow you to communicate through the Local Network Interface (LNI) in addition to the ENI. The LNI is a logical networking component that connects the Amazon EC2 instances in your Outposts subnet to your on-premises network.
The Outposts server EC2 instance local communications characteristics:
- Local network traffic needs the use of an LNI.
- The subnets on Outposts servers must be enabled for LNIs. This is done by entering the following command:
aws ec2 modify-subnet-attribute \
--subnet-id subnet-1a2b3c4d \
--enable-lni-at-device-index 1
- IP address assignment for the LNI can be DHCP or static.
- You can’t apply VPC security groups to the LNI. To control traffic on the LNI, you can use an OS based firewall, external on-premises firewall, or other security devices.
- Amazon CloudWatch metrics are produced for each LNI.
- Outposts servers don’t tag VLAN traffic. If VLAN tags are needed, then the network interface settings inside the guest OS must apply the VLAN tags. Multiple VLAN interfaces can exist within the same LNI (in this case you would be using the LNI as a VLAN trunk).
- Local traffic bandwidth performance depends on the instance type. The larger the instance type, the higher performance the throughput of the LNI. The maximum throughput is 10 Gbps.
- EC2 instances that communicate locally always have at least two interfaces: one ENI and one or more LNIs. Therefore, the instance OS’s routing table must be configured based on the desired traffic behavior.
Example configuration: Local traffic for EC2 instance on Outposts server

Figure 2: Example scenario topology
In the example scenario, we want to launch an Amazon Linux 2023 instance and route all default traffic through the local network. Eth0 is the primary interface (ENI) and is used for traffic towards the Region. Eth1 is the LNI and is used for all other traffic. A user-data script is used to make the necessary routing changes at launch.
Here is a sample user-data script. These commands run as root so there is no need to prepend each command with sudo.
User data script (my_userdata.txt):
#!/bin/bash
route add -net 172.31.0.0/16 gw 172.31.239.1
route del default gw 172.31.239.1
cp -RL /run/systemd/network/* /etc/systemd/network/
echo -e '\n[Route]\nDestination=172.31.0.0/16\nGateway=172.31.239.1\nGatewayOnLink=yes' >> /etc/systemd/network/70-ens5.network
sed -i -e 's/UseGateway=true/UseGateway=false/g' /etc/systemd/network/70- ens5.network.d/eni.conf
We can break down this script to observe the intent of each command:
route add -net 172.31.0.0/16 gw 172.31.239.1
route del default gw 172.31.239.1
When an instance is launched on Outposts server, the instance automatically has a default route that points toward the VPC through the ENI. In the example scenario, the desired configuration is to have all default traffic go through the LNI toward our on-premises LAN, not through the ENI. To accomplish this routing behavior for the ENI, we have to add a route toward the VPC and remove the default route. The first line adds a route through the VPC (172.31.0.0/16), using 172.31.239.1 as the gateway. The second line removes the default route that uses 172.31.239.1 (via the ENI) as the gateway.
Traffic not destined for the VPC routes through the LNI. This includes all local traffic and internet-bound traffic. The local network’s DHCP server provides a default-gateway in its DHCP lease. Therefore, there is already a default route assigned to the LNI. This steers any traffic without a more specific route, including internet traffic, toward the LNI.
Next, the user-data script makes the network settings persistent after reboot. The procedure varies depending on your OS. In the case of Amazon Linux 2023, it uses systemd-networkd.
cp -RL /run/systemd/network/* /etc/systemd/network/
This command copies the configuration files from the /run/systemd/network/ folder to /etc/systemd/network/. The configuration files in the /etc/systemd/network/ folder override the default settings and load during boot. The next is step is to modify the newly copied network configuration files.
echo -e '\n[Route] \nDestination=172.31.0.0/16 \nGateway=172.31.239.1 \nGatewayOnLink=yes' >> /etc/systemd/network/70-ens5.network
In this case the ENI is ens5. This line appends the static route section to the 70-ens5.network configuration file. This makes the static route added earlier in the script (route add -net 172.31.0.0/16 gw 172.31.239.1) persistent across reboots.
sed -i -e 's/UseGateway=true/UseGateway=false/g' /etc/systemd/network/70- ens5.network.d/eni.conf
Next, the user-script edits the configuration file, eni.conf, such that the default route isn’t used for the ENI at bootup. This is accomplished using sed to search and replace true with false for the UseGateway parameter.
Launching an instance with ENI and LNI
Now that the user-data script has been created, use the AWS Command Line Interface (AWS CLI) to launch an EC2 instance:
aws ec2 run-instances \
--image-id ami-051f8a213df8bc089 \
--count 1 \
--instance-type c6id.xlarge \
--key-name my_key \
--user-data file://my_userdata.txt \
--network-interfaces '[ \
  { "DeviceIndex":0, "SubnetId":"subnet-0ca6abe6b34adfcce", "Groups": ["sg-0a9f8c2200c0a56f1"] }, \
  { "DeviceIndex":1, "SubnetId":"subnet-0ca6abe6b34adfcce", "Groups": ["sg-0a9f8c2200c0a56f1"] }]' \
--tag-specifications '[{ "ResourceType":"instance","Tags":[ \
  { "Key":"Name", "Value":"server1" } ] }]'
We can break down the parameters used in the preceding command:
--image-id ami-051f8a213df8bc089 \
This specifies the Amazon Machine Image (AMI) ID. ami-051f8a213df8bc089 is the AMI ID for Amazon Linux 2023 in us-east-1.
--count 1 \
This specifies how many EC2 instances to launch. You can launch multiple at the same time.
--instance-type c6id.xlarge
This specifies the instance type. By default, Outposts 2U servers are slotted with the c6id.8xlarge instance type and Outposts 1U servers are slotted with the c6gd.8xlarge instance type. You can adjust the slotting assignment during the ordering process or you can change the slotting assignment later by using the Self-service Capacity Management feature for AWS Outposts.
--key-name my_key
This specifies the public RSA key that is added to your EC2 instance. This key must already be defined in the same Region of your AWS account.
--user-data file://my_userdata.txt
This specifies the filename that contains your user-data script (that was created previously).
{ "DeviceIndex":0, "SubnetId":"subnet-0ca6abe6b34adfcce", "Groups": ["sg-0a9f8c2200c0a56f1"] }, \
{ "DeviceIndex":1, "SubnetId":"subnet-0ca6abe6b34adfcce", "Groups": ["sg-0a9f8c2200c0a56f1"] }]' \
This specifies the network interface configuration. By default, a single network interface, the ENI, is created. This example calls for a second interface for the LNI. DeviceIndex:0 is for the ENI and doesn’t change. DeviceIndex:1 is for the LNI, which we defined when we enabled LNI for the subnet (--enable-lni-at-device-index 1). The SubnetId refers to the subnet that was created on the Outposts server. If you want to deploy to a different Outposts server, then change the SubnetId. Groups refer to the security group that you would like assigned to the ENI. Security groups aren’t supported for the LNI, thus the security group specified for DeviceIndex:1 is only to comply with the command syntax check. A security group will not be applied to the LNI.
--tag-specifications '[{ "ResourceType":"instance","Tags":[ \
{ "Key":"Name", "Value":"server1" } ] }]'
This assigns a name to the EC2 instance, which in this case is server1.
Conclusion
AWS Outposts servers allow you to run native AWS services on-premises by providing local compute. This supports workloads with low latency and data residency requirements through on-premises processing.
Although Outposts servers integrate seamlessly with the AWS cloud, there are some unique networking considerations when deploying in your data center environment. Amazon EC2 instances on the Outposts server can route traffic over the AWS global network, but you can also enable Local Network Interfaces (LNIs) to directly access your on-premises networks.
In this post we’ve demonstrated using user-data scripts during instance launch to automate hybrid cloud networking flows tailored to your requirements. With proper planning, you can use the benefits of consistent AWS services and tooling while maintaining connectivity to your existing on-premises infrastructure.
Ready to get started with hybrid cloud networking on Outposts servers? Check out the Outposts server documentation and best practices guide to begin planning your on-premises deployment.
[$] A look at Firefox forks
Post Syndicated from jzb original https://lwn.net/Articles/1012453/
Mozilla’s actions have been rubbing many Firefox fans the
wrong way as of late, and inspiring them to look for alternatives.
There are many choices for users who are looking for a browser that
isn’t part of the Chrome monoculture but is full-featured and suitable
for day-to-day use. For those who are willing to stay in the Firefox
“family” there are a number of good options that have taken vastly
different approaches. This includes GNU IceCat, Floorp, LibreWolf, and Zen.
New year, new Heroes – March 2025
Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/new-year-new-heroes-march-2025/
As we dive into 2025, we’re thrilled to announce our latest group of AWS Heroes! These exceptional individuals have demonstrated outstanding expertise and innovation, and are committed to sharing knowledge. Their contributions to the AWS community are greatly appreciated, and today we’re excited to celebrate them.
Ahmed Bebars – New Jersey, USA
 Container Hero Ahmed Bebars is a Principal Engineer at The New York Times, where he leads the design and delivery of scalable developer platforms that enhance productivity and empower engineering teams. With deep expertise in containers, Kubernetes, and cloud-native technologies, Ahmed builds robust infrastructure solutions that streamline development workflows and support innovation. As an active member of the AWS and Cloud Native communities, he frequently shares his expertise at events like KubeCon, AWS re:Invent, AWS Community Days, and Kubernetes Community Days. Through his initiative, “Level Up with Ahmed,” he shares practical insights and resources to help engineers grow their skills and stay ahead in the evolving tech landscape.
Badri Narayanan Kesavan – Singapore
 Community Hero Badri Narayanan Kesavan is an Engineering Lead and Solutions Architect with over a decade of professional experience, specializing in AWS Cloud solutions, platform engineering, and DevOps automation. Badri’s passion lies in learning and sharing with the community. He has delivered several talks at AWS Singapore Summit, AWS Summit ASEAN 2023, AWS Community Days, and various user group meetups. As an active AWS community leader, he organizes meetups and workshops under the AWS Singapore User Group where he regularly conducts sessions on diverse AWS topics, engaging a wide audience to foster innovation and collaboration. He has also authored the book “Mastering Amazon EC2)” which is a comprehensive guide to building robust and resilient applications on Amazon Elastic Compute Cloud (Amazon EC2).
Marcelo Paiva – Goiânia, Brazil
 Community Hero Marcelo Paiva has over 30 years of experience in technology and is the CTO at Softprime Soluções, leading product development and research in digital biometrics, facial recognition, and artificial intelligence (AI). With more than a decade working with cloud computing, he specializes in building scalable and innovative solutions using AWS. Passionate about tech communities, Marcelo founded the AWS User Group in Goiânia in 2018, helping grow the local community. Today, he organizes events such as JoinCommunity and Cloud Summit Cerrado, fostering learning and networking in the Cerrado region.
Raphael Jambalos – Quezon City, Philippines
 Community Hero Raphael Jambalos manages the Cloud Native development team at eCloudValley Philippines. His team has implemented dozens of cloud-native applications across multiple industries for customers in the Philippines. He is active in helping the AWS User Groups grow in the Philippines, and is passionate about connecting with the community beyond Manila. In his free time, he loves to read books and write about cloud technologies on his Dev.to blog.
Stav Ochakovski – Tel Aviv, Israel
 Container Hero Stav Ochakovski is a DevOps Engineer at Beacon and a cybersecurity expert, managing highly scalable multi-cloud environments. With a background in DevOps engineering and instruction, Stav seamlessly transitioned into the dynamic cybersecurity start-up scene. A champion of container technologies and Amazon Elastic Kubernetes Service (Amazon EKS), she brings deep expertise in Kubernetes, CI/CD pipelines, and logging solutions to the AWS community. Stav actively shares her expertise by speaking at AWS community events, as well as security and container conferences. She is also a leader of the Israel AWS User Group and is a pastry-chef school graduate and licensed skipper.
Learn More
Visit the AWS Heroes website if you’d like to learn more about the AWS Heroes program, or to connect with a Hero near you.
— Taylor
The BIGMA 300-600mm F4 hands on
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=pCHZJ6KMFZQ