Tag Archives: Technical How-to

How to evaluate and use ECDSA certificates in AWS Certificate Manager

Post Syndicated from Zachary Miller original https://aws.amazon.com/blogs/security/how-to-evaluate-and-use-ecdsa-certificates-in-aws-certificate-manager/

AWS Certificate Manager (ACM) is a managed service that enables you to provision, manage, and deploy public and private SSL/TLS certificates that you can use to securely encrypt network traffic. You can now use ACM to request Elliptic Curve Digital Signature Algorithm (ECDSA) certificates and associate the certificates with AWS services like Application Load Balancer (ALB) or Amazon CloudFront. As a result, you get the benefit of managed renewal, where ACM can automatically renew ECDSA certificates before they expire. Previously, you could only request certificates with an RSA 2048 key algorithm from ACM. ECDSA certificates could be imported to ACM, but imported certificates cannot use managed renewal.

You can request both ECDSA P-256 and P-384 certificates from ACM. If you do not request an ECDSA certificate, ACM will issue an RSA 2048 certificate by default.

In this blog post, we will briefly examine the differences between RSA and ECDSA certificates, discuss some important considerations when evaluating which certificate type to use, and walk through how you can request an ECDSA certificate and associate it with an application load balancer in AWS.

Cryptographic certificates overview

TLS certificates are used to secure network communications and establish the identity of websites over the internet, as well as the identity of resources on private networks. Public certificates that you request through ACM are obtained from Amazon Trust Services, which is an Amazon managed public certificate authority (CA).

Private certificates are issued through certificate authorities, which you can create and manage by using AWS Private Certificate Authority (AWS Private CA).

Both public and private certificates can help customers identify resources on networks and secure communication between these resources. Public certificates identify resources on the public internet, whereas private certificates do the same for private networks. One key difference is that applications and browsers trust public certificates by default, but an administrator must explicitly configure applications and devices to trust private certificates.

RSA and ECDSA primer

RSA and ECDSA are two widely used public-key cryptographic algorithms—algorithms that use two different keys to encrypt and decrypt data. In the case of TLS, a public key is used to encrypt data, and a private key is used to decrypt data. Public key (or asymmetric key) algorithms are not as computationally efficient as symmetric key algorithms like AES. For this reason, public key algorithms like RSA and ECDSA are primarily used to exchange secrets between two parties initiating a TLS connection. These secrets are then used by both parties to decipher the same symmetric key that actually encrypts the data in transit.

RSA stands for Rivest, Shamir, and Adleman: the researchers who first publicly described this algorithm in 1977. The basic functionality of RSA relies on the idea that large prime numbers are very difficult to efficiently factor. ECDSA, or Elliptic Curve Digital Signature Algorithm, is based on certain unique mathematical properties of elliptic curves that make them very useful for cryptographic operations. The cryptographic utility of ECDSA comes from a concept called the discrete logarithm problem.

Considerations when choosing between RSA and ECDSA

What are the important differences between RSA and ECDSA certificates? When should you choose ECDSA certificates to encrypt network traffic? In this section, we’ll examine the security and performance considerations that help to determine whether ECDSA or RSA certificates are the best choice for your workload.

Security

In cryptography, security is measured as the computational work it takes to exhaust all possible values of a symmetric key in an ideal cipher. An ideal cipher is a theoretical algorithm that has no weaknesses, so you must try every possible key to discover which is the correct key. This is similar to the idea of “brute forcing” a password: trying every possible character combination to find the correct password.

Let’s imagine you have a 112-bit key ideal cipher, which means it would take 2112 tries to exhaust the key space—we would say this cipher has a 112-bit security strength. However, it is important to realize that security strength and key length are not always equal—meaning that an encryption key with a length of 112 bits will not always have a 112-bit security strength.

ECDSA provides higher security strength for lower computational cost. ECDSA P-256, for example, provides 128-bit security strength and is equivalent to an RSA 3072 key. Meanwhile, ECDSA P-384 provides 192-bit security strength, equivalent to the key associated with an RSA 7680 certificate. In other words, an ECDSA P-384 key would require 2192 tries to exhaust the key space.

The following table provides an in-depth comparison of the different security strengths for RSA key lengths and ECDSA curve types. Note that only RSA 2048 and ECDSA P-256 and P-384 are currently issued by ACM. However, ACM does support the import and usage of the other certificate types listed in the table. For more information, see Importing certificates into AWS Certificate Manager.

Security strength RSA key length ECDSA curve type
80-bit 1024 160
112-bit 2048 224
128-bit 3072 256
192-bit 7680 384
256-bit 15360 512

Performance

ECDSA provides a higher security strength (for a given key length) than RSA but does not add performance overhead. For example, ECDSA P-256 is as performant as RSA 2048 while providing security strength that is comparable to RSA 3072.

ECDSA certificates also have up to a 50% smaller certificate size when compared to RSA certificates, and are therefore more suitable to protect data-in-transit over low bandwidth or for applications with limited memory and storage, such as Internet of Things (IoT) devices.

Take a look at the following certificate examples; you can see the size difference between RSA and ECDSA certificates.

RSA 2048: ECDSA P-256 (EC_prime256v1):
-----BEGIN CERTIFICATE-----
MIIDLjCCAhYCCQCgZT9jmNNbmjANBgkqhkiG9w0BAQsFADBZMQswCQYDVQQGEwJV
UzETMBEGA1UECAwKV2FzaGluZ3RvbjEQMA4GA1UEBwwHU2VhdHRsZTEPMA0GA1UE
CgwGQW1hem9uMRIwEAYDVQQDDAllY2RzYWJsb2cwHhcNMjIxMDE4MTcxMTUyWhcN
MjMxMDE4MTcxMTUyWjBZMQswCQYDVQQGEwJVUzETMBEGA1UECAwKV2FzaGluZ3Rv
bjEQMA4GA1UEBwwHU2VhdHRsZTEPMA0GA1UECgwGQW1hem9uMRIwEAYDVQQDDAll
Y2RzYWJsb2cwggEiMA0GCSqGSIb3DQEBAQUAA4IBDwAwggEKAoIBAQC64mquZoJ5
tJVmiUK0vKRYyYqHYYV/sTqwcW2u7MNP/mvCWd6K8rFBcxdBcscGFZR5tZa7OzTu
XUdwqdj13Gjl/euG4c8rlIWY+5HtybXI7vBRrf6YCNZWIAucRQesycmhtf9bjB7v
mgBpy7XVEweBZ++Ve3IynsNBD0O4C0w5y1HuaFFCsxF+dsrcgofVIMcjIEs/by65
JqIQMvjDExjxkkSFfyhrSd3f78EDp3WtEATD67zMTZGKgHNc1J/7V7vMRfb0qyqr
WxWUQVMRMzo1LdC3vpF57aMP/b6amQBSU5lP0nMBLfqA3oHQ3hvXEUaNrxcvHdyb
CUmd9On5cPMjAgMBAAEwDQYJKoZIhvcNAQELBQADggEBAGudUVlz0x/OJGCORjoo
KuGjvlY2pztMkj3KA6/DO2eYYeYwrAcBuO7Ycc18XDnTwGfsZmkV1INVd2NNoqSX
PxsY21y/7ely8ZK1f7lMCtxWaHdlz4nzxtrEN/YRrFZ0VoGmBgQutRou0fIdn9ax
+J4zUwDQYqXyppIqTmSxajvzrfl0YYUZ5xd4gGGTLah7gzqqv2H/KTAUck0mr9B7
o3hh9Oe8MNsUJhMp1s1c8MTOZzvY+yadDlG4zIXKdZPUxuAvdxpWPEWntsPQIxo7
8m09RAttvA+/WKfuXbCXNILj9MwH6cRAnq/8DVFmgWnZIz4YSpNk9TinN3U0hcoi
PU4=
-----END CERTIFICATE-----
-----BEGIN CERTIFICATE-----
MIIBoTCCAUgCCQD+ccox1RgzgTAKBggqhkjOPQQDAjBZMQswCQYDVQQGEwJVUzET
MBEGA1UECAwKV2FzaGluZ3RvbjEQMA4GA1UEBwwHU2VhdHRsZTEPMA0GA1UECgwG
QW1hem9uMRIwEAYDVQQDDAllY2RzYWJsb2cwHhcNMjIxMDE4MTcwNzAzWhcNMjMx
MDE4MTcwNzAzWjBZMQswCQYDVQQGEwJVUzETMBEGA1UECAwKV2FzaGluZ3RvbjEQ
MA4GA1UEBwwHU2VhdHRsZTEPMA0GA1UECgwGQW1hem9uMRIwEAYDVQQDDAllY2Rz
YWJsb2cwWTATBgcqhkjOPQIBBggqhkjOPQMBBwNCAASsxNpbxi5xcRwIBN1M1M4s
tDyyPILqwGjlvfruLZDqPHB7EVSV78TjN4+/a3KO0bl8cYolLBm31rlLAxZfejgK
MAoGCCqGSM49BAMCA0cAMEQCIF7FSzRha4KATIgj8C6i0NfNomHAX8I0lPtMgHrN
YGOOAiAlBpqNQU8e2i9zHzU9rQx7rZJnm4iepImKvodfSCXJ/A==
-----END CERTIFICATE-----

Consider a small IoT sensor device that tracks temperature in an office building. This device typically has very low storage capacity and compute power, so the smaller ECDSA certificate will be easier to process and store. In the case of an IoT device, you might not be able to store the entire RSA certificate chain on the device due to memory limitations and the larger size of RSA certificates. This can make it more difficult to validate the chain of trust for that certificate.

Using ECDSA, customers can take advantage of the smaller size of the certificates (and the certificate trust chain) and store the entire chain of trust on the IoT device itself, enabling the IoT device to more easily validate the certificate.

When should I use ECDSA certificates from ACM?

In general, you should consider using ECDSA certificates wherever possible, because they provide stronger security (for a given key length) compared to RSA, without impacting performance. You can also choose to issue ECDSA certificates from ACM to implement 128-bit or 192-bit TLS security, where previously you could request up to 112-bit security from ACM by using RSA 2048 certificates.

ECDSA certificates are strongly recommended for applications that need to securely send data over low-bandwidth connections, or when you are using IoT devices that might not have much memory or computational power to store and process the larger certificate sizes that RSA offers.

If your application is not ECDSA compatible, you will need to continue using RSA certificates. RSA 2048 remains the default certificate type issued by ACM, in order to prevent compatibility issues with legacy applications or with applications that do not support ECDSA certificate types. We will provide links to check if your application is compatible with ECDSA certificate types in the next section of this blog.

Getting started with ECDSA certificates

Modern browsers and operating systems are ECDSA compatible. That said, some custom applications might not be ECDSA compatible. You can check whether your calling application is ECDSA compatible by accessing the following links from your application:

ECDSA P-256

ECDSA P-384

When you access one of these links, you should see a message stating “Expected Status: good”. This indicates that the application is ECDSA compatible. See Figure 1 for an example of a successful result.

Figure 1: ECDSA application compatibility example

Figure 1: ECDSA application compatibility example

When you terminate your TLS traffic with ALB, you can work around compatibility concerns by binding both ECDSA and RSA certificates for a given domain. ALB will prioritize and present the ECDSA certificate when the calling application is ECDSA compatible and will use the RSA certificate if the calling application is not ECDSA compatible. We’ll walk through this configuration in the demonstration portion of this post.

How to request an ECDSA certificate from ACM

You can use the ACM console, APIs, or AWS Command Line Interface (AWS CLI) to issue public or private ECDSA P-256 and P-384 TLS certificates. When you request certificates by using the API or AWS CLI, you can use the request-certificate API action with either EC_prime256v1 or EC_secp384r1 as the key-algorithm parameter to request a P-256 or P-384 ECDSA certificate, respectively.

Certificates have a defined validity period, and ACM will attempt to renew certificates that were issued by ACM and that are in use before they expire. ACM will also attempt to automatically bind the renewed certificates with an integrated service. ACM issued private ECDSA certificates can also be exported and used on other workloads to terminate TLS traffic.

Associate an ECDSA certificate with an Application Load Balancer for TLS

To demonstrate how to request and use ECDSA certificates from ACM, let’s examine a common use case: requesting a public certificate from ACM and associating it with an ALB. This walkthrough will also include requesting an RSA 2048 certificate and associating it with the same ALB, to facilitate TLS connections for applications that do not support ECDSA. ALB will prioritize and present the ECDSA certificate when the calling application is ECDSA compatible, and will use the RSA certificate if the calling application is not ECDSA compatible.

This procedure has the following prerequisites:

  • An AWS Identity and Access Management (IAM) user or role that has the appropriate permissions to request certificates from ACM and create an ALB
  • A public domain that you own
  • A public subnet, or IAM permissions to create one

To request an ECDSA certificate from ACM

  1. Navigate to the ACM console and choose Request a certificate.
  2. Choose Request a public certificate, and then choose Next.
  3. For Fully qualified domain name, enter your domain name.
  4. Choose DNS validation. DNS validation is recommended wherever possible, because it enables automatic renewal of ACM issued certificates with no action required by the domain owner. If you use Amazon Route 53, you can use ACM to directly update your DNS records. DNS-validated certificates will be renewed by ACM as long as the certificate is in use and the DNS record is in place.
    Figure 2: Requesting a public ECDSA certificate

    Figure 2: Requesting a public ECDSA certificate

  5. In the Key algorithm options section, select your preferred algorithm based on your security requirements:
    • ECDSA P-256 — Equivalent in security strength to RSA 3072
    • ECDSA P-384 — Equivalent in security strength to RSA 7680
    Figure 3: Key algorithms

    Figure 3: Key algorithms

  6. (Optional) Add tags to help you identify and manage your certificate. You can find more information on using tags in Tagging AWS resources in the AWS General Reference.
  7. Choose Request to request the public certificate.

    The certificate will now be in the Pending Validation state until the domain can be validated, either through DNS or email validation, depending on your selection in the previous steps. For information on how to validate ownership of the domain name or names, see Validating domain ownership in the AWS Certificate Manager User Guide.

  8. Take note of the certificate ARN; you will need this later to identify the certificate.

To request an RSA 2048 certificate from ACM

  1. To request a public RSA 2048 certificate, use the same steps noted in the preceding section, but select RSA 2048 in the Key algorithm options section.
  2. Make sure that both certificates you request have the same fully qualified domain name.

    For more information on requesting public certificates from ACM, see Requesting a public certificate.

To create a new Application Load Balancer and associate a default certificate

  1. Navigate to the Amazon Elastic Compute Cloud (EC2) console. In the left navigation pane, under Load Balancing, choose Load Balancers.
  2. Choose Create Load Balancer.

    For this post, we will use an Application Load Balancer. You can view more details on each type of Load Balancer, and see a feature-to-feature breakdown, on the Elastic Load Balancing features page.

  3. For the Application Load Balancer type, choose Create.
  4. Enter a name for your load balancer.
  5. Select the scheme and IP address type of the application load balancer. For this post, we will choose Internet-facing for the scheme and use the IPv4 address type.
    Figure 4: Create an application load balancer

    Figure 4: Create an application load balancer

  6. In the Network mapping section of this page, you will need to select a VPC and at least two Availability Zones and one public subnet per zone. If you do not already have a public subnet in two Availability Zones, see these instructions for creating a public subnet.
    Figure 5: Network mapping for ALB

    Figure 5: Network mapping for ALB

  7. Next, you need to create a secure listener. Under Listeners and routing, choose the HTTPS protocol (Port 443) in the drop-down list.
  8. Under Default action, choose Forward. For Target Group, select a target group for the ALB to send traffic to.
  9. Under Secure listener settings, you will associate the RSA 2048 certificate with the new Application Load Balancer.

    Choose the appropriate security policy for your organization—you can compare policies on this page.

  10. Under Default SSL/TLS certificate, verify that From ACM is selected, and then in the drop-down list, select the RSA certificate you requested earlier.

    Note: We are using the RSA certificate as the default so that the ALB will use this certificate if the connecting client does not support ECDSA or the Server Name Indication (SNI) protocol. This is to maximize availability and compatibility with legacy applications.

    Figure 6: Secure listener settings

    Figure 6: Secure listener settings

  11. (Optional) Add tags to the Application Load Balancer.
  12. Review your selections, and then choose Create load balancer.
    Figure 7: Review and create load balancer

    Figure 7: Review and create load balancer

To associate the ECDSA certificate with the Application Load Balancer

  1. In the EC2 console, select the new ALB you just created, and choose the Listeners tab.
  2. In the SSL Certificate column, you should see the default certificate you added when you created the ALB. Choose View/edit certificates to see the full list of certificates associated with this ALB.
    Figure 8: ALB listeners

    Figure 8: ALB listeners

  3. Under Listener certificates for SNI, choose Add certificate.
    Figure 9: Listener certificates for SNI

    Figure 9: Listener certificates for SNI

  4. Under ACM and IAM certificates, select the ECDSA certificate you requested earlier.

    Note: You can use the certificate ARN to identify the appropriate certificate.

  5. Choose Include as pending below to add the ECDSA certificate to the listener.
    Figure 10: Adding the ECDSA certificate to the load balancer listener

    Figure 10: Adding the ECDSA certificate to the load balancer listener

  6. Under Listener certificates for SNI, confirm that the ECDSA certificate is listed as pending, and choose Add pending certificates.
    Figure 11: Confirm addition of pending certificates

    Figure 11: Confirm addition of pending certificates

Great! We’ve used ACM to request a public ECDSA certificate and a public RSA 2048 certificate. Next, we associated both of these certificates with an Application Load Balancer to facilitate TLS communications between the load balancer and client devices.

If clients support the SNI protocol, the ALB uses a smart certificate selection algorithm. The load balancer will select the best certificate that the client can support from the certificate list. Certificate selection is based on the following criteria, in the following order:

  • Public key algorithm (prefer ECDSA over RSA)
  • Hashing algorithm (prefer SHA over MD5)
  • Key length (prefer the longest key)
  • Validity period

In the earlier example, this means if clients support SNI and ECDSA, the ECDSA certificate will be prioritized and presented to the client. If the client does not support SNI or ECDSA, the RSA certificate will be used to maximize compatibility with legacy applications.

Conclusion

In this blog post, we discussed the basic differences between RSA and ECDSA certificates, when you might choose ECDSA over RSA, and how you can use AWS Certificate Manager to request public or private ECDSA certificates. We also covered how to request a public ECDSA certificate from ACM and associate it with an Application Load Balancer. Finally, we showed you how to request an RSA 2048 certificate and associate it with the same load balancer to facilitate TLS for applications that do not support ECDSA certificates.

To learn more about using ACM to issue ECDSA certificates, see our YouTube video: AWS Certificate Manager (ACM) – How to evaluate and use ECDSA certificates. You can also refer to the AWS Certificate Manager documentation for more details, and then get started issuing ECDSA certificates with AWS Certificate Manager.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.
Zach Miller

Zach Miller

Zach is a Senior Security Specialist Solutions Architect at AWS. His background is in data protection and security architecture, focused on a variety of security domains, including cryptography, secrets management, and data classification. Today, he is focused on helping enterprise AWS customers adopt and operationalize AWS security services to increase security effectiveness and reduce risk.

Chandan Kundapur

Chandan Kundapur

Chandan is a Senior Technical Product Manager on the AWS Certificate Manager (ACM) team. With over 15 years of cybersecurity experience, he has a passion for driving PKI product strategy.

Optimize your sending reputation and deliverability with SES dedicated IPs

Post Syndicated from Lauren Cudney original https://aws.amazon.com/blogs/messaging-and-targeting/optimize-your-sending-reputation-and-deliverability-with-ses-dedicated-ips/

Optimize your sending reputation and deliverability with SES dedicated IPs

Email remains the best medium for communicating with customers, with a ROI of 4200%, higher than social media or blogs. Organizations that fail to adequately manage their email sending and reputation risk having their emails marked as spam, not reaching their customers’ inboxes, reducing trust with their customers and ultimately, losing revenue. Studies showed that 16% of all marketing emails have either gone completely missing or have been caught by popular spam filters. In this blog post we will explain the benefits of sending email over a dedicated IP, and how dedicated IPs (managed) makes it easy to do so.

Improve your sender reputation and deliverability with dedicated IPs
When customers sign up to SES, their sending is automatically sent from shared IPs. Shared IPs offer a cost-effective and safe method of sending email. A limitation of sending over a shared IP is that customers do not control their own sending reputations. The reputation of the IP that you send from is determined by the quality of content and engagement levels of all the emails sent from that IP. This means that good senders, that send highly engaged content or important transactional emails, cannot improve their sending reputation on shared IPs. By improving their sending reputation, senders can improve their deliverability rates and make sure that more of their emails get to to the recipient’s inbox rather than their junk folder. Today, this is avoided by customers sending via a dedicated IP. Dedicated IPs are exclusive to a single sender so other bad actors cannot affect their sending reputation and good senders can improve their sending reputation.

A common method organizations use to increase delivery rate is to lease dedicated IPs where they are the sole exclusive sender and do not share their IP with other senders. This helps grow and maintain sending reputation and build high levels of trust with ISPs and mailbox vendors, ensuring high delivery rates. Today however, there are a number of issues with sending email via dedicated IPs. Customers experience difficulties in estimating how many dedicated IPs they need to handle their sending volume. This means that customers often lease too many IPs and pay for bandwidth that they don’t need. Dedicated IPs must also be “warmed-up” by sending a gradually increasing amount of email each day via the IP so that the recipient ISPs and mailboxes do not see a sudden large burst of emails coming from it, which is a signal of spam and can result in a blocking. Customers must manually configure the amount of mail to increase by, often not reaching the required volume, on average, after 45 days, hampering their time-to-market agility. This burden of provisioning, configuring and managing dedicated IPs inhibits many email senders from adopting them, meaning that their sending reputation is not optimized.

Dedicated IPs (managed)
SES customers can now send their email via dedicated IPs (managed) and will have the entire process of provisioning, leasing, warming up and managing the IP fully automated. Dedicated IPs (managed) is a feature of SES that simplifies how SES customers setup and maintain email sending through a dedicated IP space. It builds on learnings and feedback gathered from customers using the current standard Dedicated IP offering.

Dedicated IPs (managed) provides the following key benefits:

  • Easy Onboarding – Customers can create a managed dedicated pool through the API/CLI/Console and start with dedicated sending, without having to open AWS support cases to lease/release individual IPs.
  • Auto-Scaling per ISP – No more manual monitoring or scaling of dedicated pools. The pool scales out and in automatically based on usage. This auto-scaling also takes into consideration ISPs specific policies. For example, if SES detects that an ISP supports a low daily send quota, the pool will scale-out to better distribute traffic to that ISP across more IPs. In the current offering, customers are responsible for right sizing the number of IPs in their sending pools.
  • Warmup per ISP – SES will track the warmup level for each IP in the pool toward each ISP individually. SES will also track domain reputation at the individual ISP level. If a customer has been sending all their traffic to Gmail, the IP is considered warmed up only for Gmail and cold for other ISPs. If the traffic pattern changes and customer ramps up their traffic to Hotmail, SES will ramp up traffic slowly for Hotmail as the IPs are not warmed up yet. In the current manual dedicated offering, warmup % is tracked at the aggregate IP level and therefore can’t track the individual ISP level of granularity.
  • Adaptive warmup – The warmup % calculation is adaptive and takes into account actual sending patterns at an ISP level. When the sending to an ISP drops, the warmup % also drops for the given ISP. Today, when warming up the IP, customers must specify a warm up schedule and choose their volumes. Rather than having to specify a schedule and guess the optimal volume to send, Dedicated IPs (managed) will adapt the sending volume based on each individual ISP’s capacity, optimizing the warm-up schedule
  • Spill-over into shared & defer – Messages will be accepted through the API/SMTP and the system will be deferring and retrying excess sending from a customer when it is above what the pool can safely support for a particular ISP. In the early phases of the pool, the system will still leverage spill-over into shared as is done in the current offering.

Onboarding

If you use several dedicated IP addresses with Amazon SES, you can create groups of those addresses. These groups are called dedicated IP pools. A common scenario is to create one pool of dedicated IP addresses for sending marketing communications, and another for sending transactional emails. Your sender reputation for transactional emails is then isolated from that of your marketing emails. In this scenario, if a marketing campaign generates a large number of complaints, the delivery of your transactional emails is not impacted.

Configuration sets are groups of rules that you can apply to your verified identities. A verified identity is a domain, subdomain, or email address you use to send email through Amazon SES. When you apply a configuration set to an email, all of the rules in that configuration set are applied to the email. For example, you can associate these dedicated IP pools with configuration sets and use one for sending marketing communications, and another for sending transactional emails.

Onboarding to a managed dedicated pool for the most part is very similar to onboarding to regular dedicated IP sending. It involves creating a dedicated on demand pool, associating the pool with a configuration set, and specifying the configuration set to use when sending email. The configuration set can be also applied implicitly to a sending identity by using the default configuration set feature.

Below are the instructions of how to get set up on dedicated IPs (managed)

Instructions

Console

Customer accounts allow-listed for the feature preview will be able to configure and view the relevant SES resources through the SES Console UI as well.

1. Go to the SES AWS console and click on Dedicated IPs
2. On the Dedicated IPs Screen, select the Dedicated IPs (managed) tab
3. Clink on the “Create dedicated on demand IP Pool” button
4. Enter the details of your new dedicated on demand pool. Specify Scaling Mode to be “OnDemand”. Do not associate it with a Configuration Set at this point. Click create.
5. Going back to the dedicated IP on demand pool view, you should see your newly created dedicated IPs (managed) pool in the “IP pools” table. If you have any existing standard dedicated pools, you can view them and their individual IPs under the “Standard dedicated IPs” tab.
6. View your current configuration sets.
7. Click on the “Create set” button.
8. Enter the details of your new configuration set. For Sending IP pool select your newly created dedicated on demand IP pool and click create.
9. View your verified sending identities and click on the identity you wish to onboard to dedicated sending.
10. Select the configuration tab. Under default configuration set, click on the Edit button.
11. Click on the “Assign a default configuration set” checkbox and select your newly created configuration set. Click save.
12. At this point all sending from that verified identity will automatically be sent using the dedicated on demandpool.

CLI

The dedicated on demand pool feature is currently in preview and not yet available through the public CLI. If you wish to configure or view your SES resources through the CLI, you can download and add an internal preview sesv2 model that contains the relevant API changes. A dedicated pool can be specified to be managed by setting the –scaling-mode MANAGED parameter when creating the dedicated pool.

wget https://tiny.amazon.com/qjdb5ewf/seses3amazemaidedijson -O "email-2019-09-27.dedicated-pool-managed.json"

aws configure add-model —service-model file://email-2019-09-27.dedicated-pool-managed.json —service-name sesv2-dedicated-managed

export AWS_DEFAULT_REGION=eu-central-1

# Create a managed dedicated pool
aws sesv2-dedicated-managed create-dedicated-ip-pool --pool-name dedicated1 --scaling-mode MANAGED

# Create a configuration set that that will send through the dedicated pool
aws sesv2-dedicated-managed create-configuration-set --configuration-set-name cs_dedicated1 --delivery-options SendingPoolName=dedicated1

# Configure the configuration set as the default for your sending identity
aws sesv2 put-email-identity-configuration-set-attributes --email-identity {{YOUR-SENDING-IDENTITY-HERE}} --configuration-set-name cs_dedicated1

# Send SES email through the API or SMTP without requiring any code changes. Emails will # be sent out through the dedicated pool.
aws ses send-email --destination ToAddresses={{DESTINATION-GOES-HERE}} --from {{YOUR-SENDING-IDENTITY-HERE}} --message "Subject={Data='Sending via managed ',Charset=UTF-8},Body={Text={Data=thebody,Charset=UTF-8}}"

Monitoring

We recommend customers onboard to event destinations [6] and delivery delay events [7] to more accurately track the sending performance of their dedicated sending.

Conclusion

In this blog post we explained the benefits of sending via a dedicated IP and the ease at which you can now do this using the new dedicated IPs (managed) feature.

For more information, please visit the below links:

https://docs.aws.amazon.com/ses/latest/dg/dedicated-ip.html 
https://docs.aws.amazon.com/ses/latest/dg/dedicated-ip-pools.html 
https://docs.aws.amazon.com/ses/latest/dg/managing-ip-pools.html
https://docs.aws.amazon.com/ses/latest/dg/using-configuration-sets-in-email.html
https://docs.aws.amazon.com/ses/latest/dg/managing-configuration-sets.html#default-config-sets
https://docs.aws.amazon.com/ses/latest/dg/monitor-using-event-publishing.html
https://aws.amazon.com/about-aws/whats-new/2020/06/amazon-ses-can-now-send-notifications-when-the-delivery-of-an-email-is-delayed/
https://docs.aws.amazon.com/ses/latest/dg/dedicated-ip-warming.html
https://docs.aws.amazon.com/ses/latest/dg/dedicated-ip-warming.html#dedicated-ip-auto-warm-up
https://docs.aws.amazon.com/ses/latest/dg/using-configuration-sets.html

https://dma.org.uk/uploads/misc/marketers-email-tracker-2019.pdf
https://www.emailtooltester.com/en/email-deliverability-test/

Use Amazon Inspector to manage your build and deploy pipelines for containerized applications

Post Syndicated from Scott Ward original https://aws.amazon.com/blogs/security/use-amazon-inspector-to-manage-your-build-and-deploy-pipelines-for-containerized-applications/

Amazon Inspector is an automated vulnerability management service that continually scans Amazon Web Services (AWS) workloads for software vulnerabilities and unintended network exposure. Amazon Inspector currently supports vulnerability reporting for Amazon Elastic Compute Cloud (Amazon EC2) instances and container images stored in Amazon Elastic Container Registry (Amazon ECR).

With the emergence of Docker in 2013, container technology has quickly moved from the experimentation phase into a viable production tool. Many customers are using containers to modernize their existing applications or as the foundations for new applications or services that they build. In this blog post, we’ll explore the process that Amazon Inspector takes to scan container images. We’ll also show how you can integrate Amazon Inspector into your containerized application build and deployment pipeline, and control pipeline steps based on the results of an Amazon Inspector container image scan.

Solution overview and walkthrough

The solution outlined in this post covers a deployment pipeline modeled in AWS CodePipeline. The source for the pipeline is AWS CodeCommit, and the build of the container image is performed by AWS CodeBuild. The solution uses a collection of AWS Lambda functions and an Amazon DynamoDB table to evaluate the container image status and make an automated decision about deploying the container image. Finally, the pipeline has a deploy stage that will deploy the container image into an Amazon Elastic Container Service (Amazon ECS) cluster. In this section, I’ll outline the key components of the solution and how they work. In the following section, Deploy the solution, I’ll walk you through how to actually implement the solution.

Although this solution uses AWS continuous integration and continuous delivery (CI/CD) services such as CodePipeline and CodeBuild, you can also build similar capabilities by using third-party CI/CD solutions. In addition to CodeCommit, other third-party code repositories such as GitHub or Amazon Simple Storage Service (Amazon S3) can be substituted in as a source for the pipeline.

Solution architecture

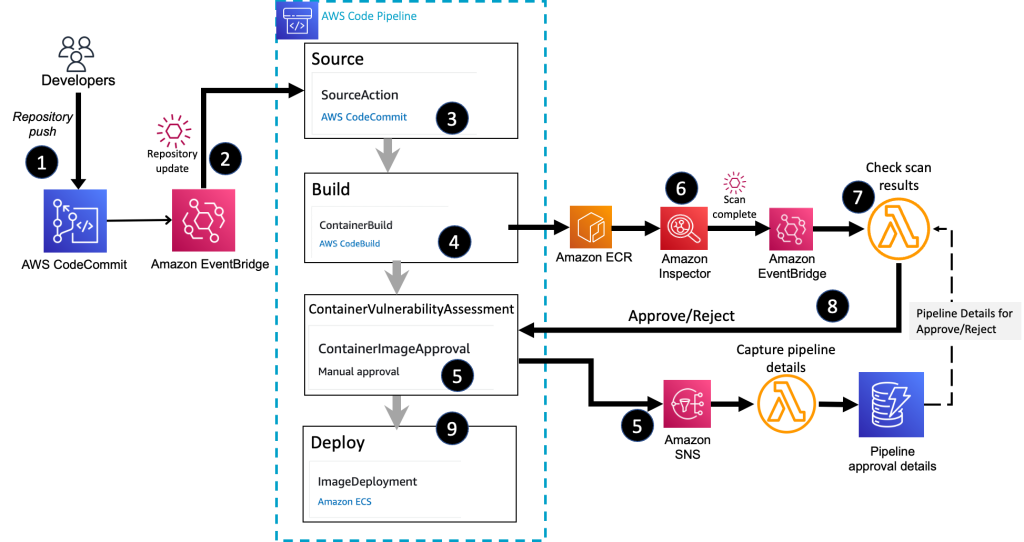
Figure 1 shows the high-level architecture of the solution, which integrates Amazon Inspector into a container build and deploy pipeline.

Figure 1: Overall container build and deploy architecture

Figure 1: Overall container build and deploy architecture

The high-level workflow is as follows:

  1. You commit the image definition to a CodeCommit repository.
  2. An Amazon EventBridge rule detects the repository commit and initiates the container pipeline.
  3. The source stage of the pipeline pulls the image definition and build instructions from the CodeCommit repository.
  4. The build stage of the pipeline creates the container image and stores the final image in Amazon ECR.
  5. The ContainerVulnerabilityAssessment stage sends out a request for approval by using an Amazon Simple Notification Service (Amazon SNS) topic. A Lambda function associated with the topic stores the details about the container image and the active pipeline, which will be needed in order to send a response back to the pipeline stage.
  6. Amazon Inspector scans the Amazon ECR image for vulnerabilities.
  7. The Lambda function receives the Amazon Inspector scan summary message, through EventBridge, and makes a decision on allowing the image to be deployed. The function retrieves the pipeline approval details so that the approve or reject message is sent to the correct active pipeline stage.
  8. The Lambda function submits an Approved or Rejected status to the deployment pipeline.
  9. CodePipeline deploys the container image to an Amazon ECS cluster and completes the pipeline successfully if an approval is received. The pipeline status is set to Failed if the image is rejected.

Container image build stage

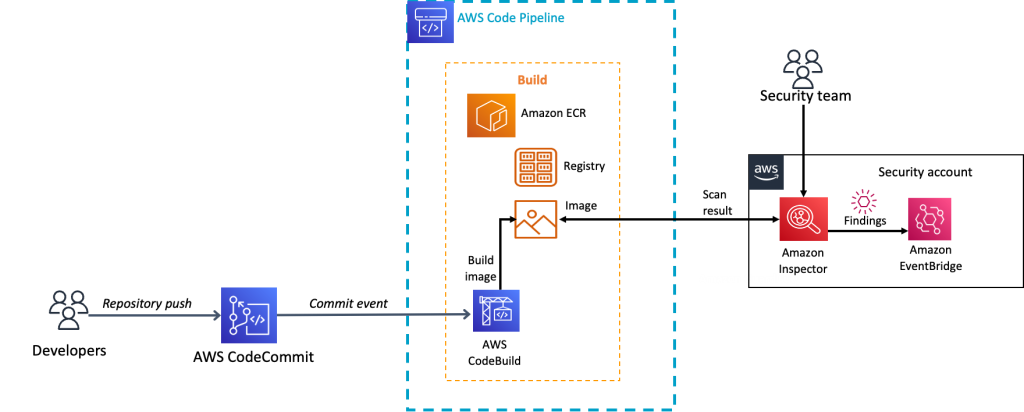
Let’s now review the build stage of the pipeline that is associated with the Amazon Inspector container solution. When a new commit is made to the CodeCommit repository, an EventBridge rule, which is configured to look for updates to the CodeCommit repository, initiates the CodePipeline source action. The source action then collects files from the source repository and makes them available to the rest of the pipeline stages. The pipeline then moves to the build stage.

In the build stage, CodeBuild extracts the Dockerfile that holds the container definition and the buildspec.yaml file that contains the overall build instructions. CodeBuild creates the final container image and then pushes the container image to the designated Amazon ECR repository. As part of the build, the image digest of the container image is stored as a variable in the build stage so that it can be used by later stages in the pipeline. Additionally, the build process writes the name of the container URI, and the name of the Amazon ECS task that the container should be associated with, to a file named imagedefinitions.json. This file is stored as an artifact of the build and will be referenced during the deploy phase of the pipeline.

Now that the image is stored in an Amazon ECR repository, Amazon Inspector scanning begins to check the image for vulnerabilities.

The details of the build stage are shown in Figure 2.

Figure 2: The container build stage

Figure 2: The container build stage

Container image approval stage

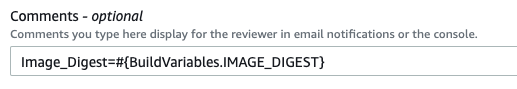
After the build stage is completed, the ContainerVulnerabilityAssessment stage begins. This stage is lightweight and consists of one stage action that is focused on waiting for an Approved or Rejected message for the container image that was created in the build stage. The ContainerVulnerabilityAssessment stage is configured to send an approval request message to an SNS topic. As part of the approval request message, the container image digest, from the build stage, will be included in the comments section of the message. The image digest is needed so that approval for the correct container image can be submitted later. Figure 3 shows the comments section of the approval action where the container image digest is referenced.

Figure 3: Container image digest reference in approval action configuration

Figure 3: Container image digest reference in approval action configuration

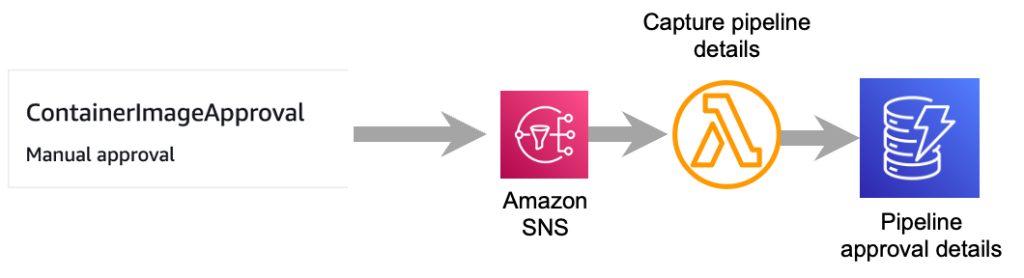
The SNS topic that the pipeline approval message is sent to is configured to invoke a Lambda function. The purpose of this Lambda function is to pull key details from the SNS message. Details retrieved from the SNS message include the pipeline name and stage, stage approval token, and the container image digest. The pipeline name, stage, and approval token are needed so that an approved or rejected response can be sent to the correct pipeline. The container image digest is the unique identifier for the container image and is needed so that it can be associated with the correct active pipeline. This information is stored in a DynamoDB table so that it can be referenced later when the step that assesses the result of an Amazon Inspector scan submits an approved or rejected decision for the container image. Figure 4 illustrates the flow from the approval stage through storing the pipeline approval data in DynamoDB.

Figure 4: Flow to capture container image approval details

Figure 4: Flow to capture container image approval details

This approval action will remain in a pending status until it receives an Approved or Rejected message or the timeout limit of seven days is reached. The seven-day timeout for approvals is the default for CodePipeline and cannot be changed. If no response is received in seven days, the stage and pipeline will complete with a Failed status.

Amazon Inspector and container scanning

When the container image is pushed to Amazon ECR, Amazon Inspector scans it for vulnerabilities.

In order to show how you can use the findings from an Amazon Inspector container scan in a build and deploy pipeline, let’s first review the workflow that occurs when Amazon Inspector scans a container image located in Amazon ECR.

Figure 5: Image push, scan, and notification workflow

Figure 5: Image push, scan, and notification workflow

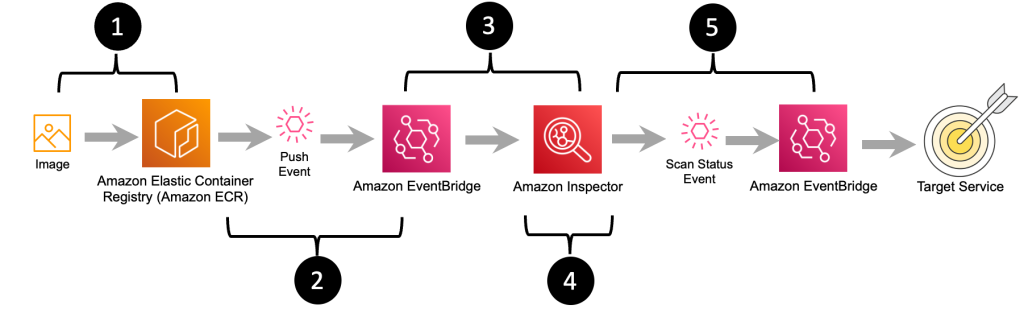
The workflow diagram in Figure 5 outlines the steps that happen after an image is pushed to Amazon ECR all the way to messaging that the image has been successfully scanned and what the final scan results are. The steps in this workflow are as follows:

  1. The final container image is pushed to Amazon ECR by an individual or as part of a build.
  2. Amazon ECR sends a message indicating that a new image has been pushed.
  3. The message about the new image is received by Amazon Inspector.
  4. Amazon Inspector pulls a copy of the container image from Amazon ECR and performs a vulnerability scan.
  5. When Amazon Inspector is done scanning the image, a message summarizing the severity of vulnerabilities that were identified during the container image scan is sent to Amazon EventBridge. You can create EventBridge rules that match the vulnerability summary message to route the message onto a target for notifications or to enable further action to be taken.

Here’s a sample EventBridge pattern that matches the scan summary message from Amazon Inspector.

{
  "detail-type": ["Inspector2 Scan"],
  "source": ["aws.inspector2"]
}

This entire workflow, from ingesting the initial image to sending out the status on the Amazon Inspector scan, is fully managed. You just focus on how you want to use the Amazon Inspector scan status message to govern the approval and deployment of your container image.

The following is a sample of what the Amazon Inspector vulnerability summary message looks like. Note, in bold, the container image Amazon Resource Name (ARN), image repository ARN, message detail type, image digest, and the vulnerability summary.

{
    "version": "0",
    "id": "bf67fc08-f522-f598-6946-8e7b372ba426",
    "detail-type": "Inspector2 Scan",
    "source": "aws.inspector2",
    "account": "<account id>",
    "time": "2022-05-25T16:08:17Z",
    "region": "us-east-2",
    "resources":
    [
        "arn:aws:ecr:us-east-2:<account id>:repository/vuln-images/vulhub/rsync"
    ],
    "detail":
    {
        "scan-status": "INITIAL_SCAN_COMPLETE",
        "repository-name": "arn:aws:ecr:us-east-2:<account id>:repository/vuln-images/vulhub/rsync",
        "finding-severity-counts": { "CRITICAL": 3, "HIGH": 16, "MEDIUM": 4, "TOTAL": 24 },
        "image-digest": "sha256:21ae0e3b7b7xxxx",
        "image-tags":
        [
            "latest"
        ]
    }
}

Processing Amazon Inspector scan results

After Amazon Inspector sends out the scan status event, a Lambda function receives and processes that event. This function needs to consume the Amazon Inspector scan status message and make a decision about whether the image can be deployed.

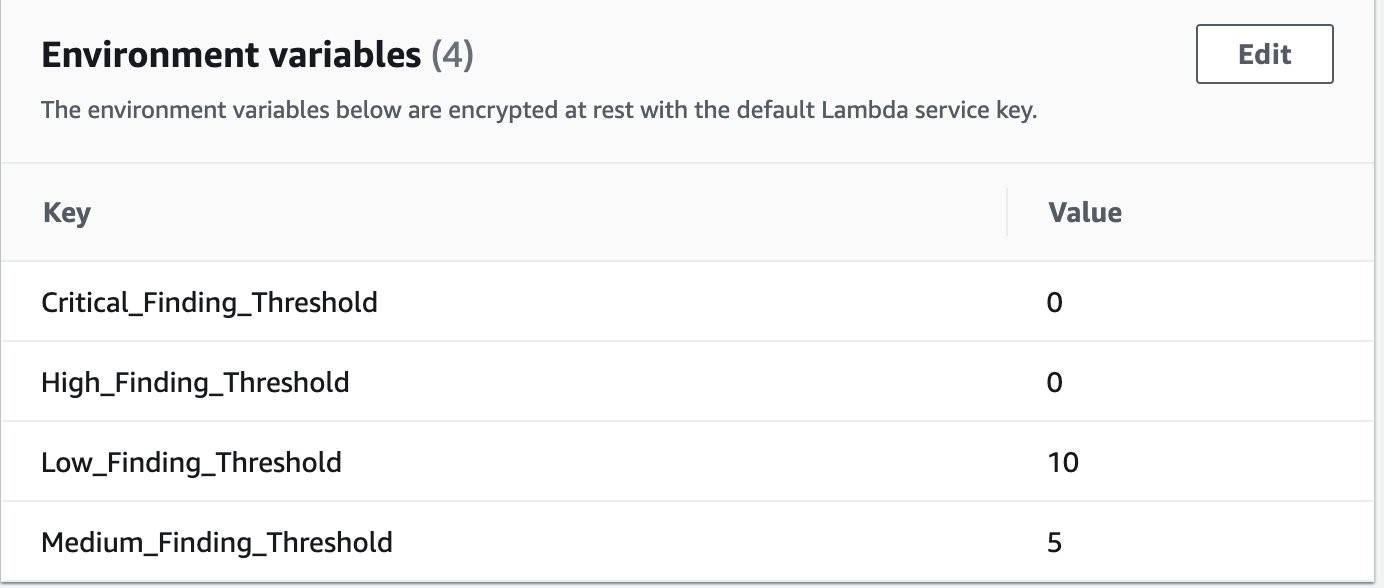
The eval_container_scan_results Lambda function serves two purposes: The first is to extract the findings from the Amazon Inspector scan message that invoked the Lambda function. The second is to evaluate the findings based on thresholds that are defined as parameters in the Lambda function definition. Based on the threshold evaluation, the container image will be flagged as either Approved or Rejected. Figure 6 shows examples of thresholds that are defined for different Amazon Inspector vulnerability severities, as part of the Lambda function.

Figure 6: Vulnerability thresholds defined in Lambda environment variables

Figure 6: Vulnerability thresholds defined in Lambda environment variables

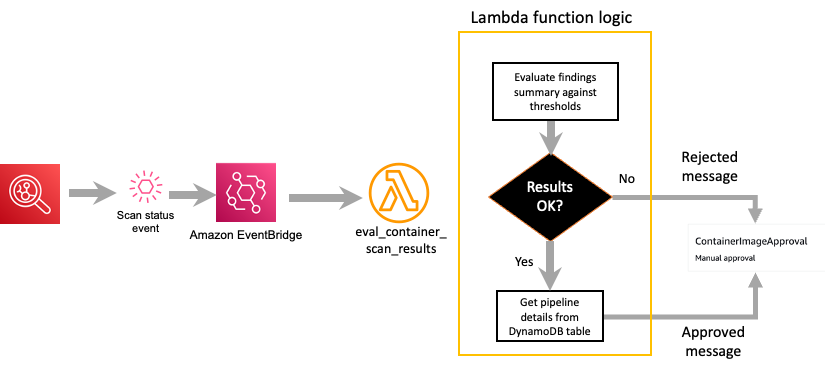
Based on the container vulnerability image results, the Lambda function determines whether the image should be approved or rejected for deployment. The function will retrieve the details about the current pipeline that the image is associated with from the DynamoDB table that was populated by the image approval action in the pipeline. After the details about the pipeline are retrieved, an Approved or Rejected message is sent to the pipeline approval action. If the status is Approved, the pipeline continues to the deploy stage, which will deploy the container image into the defined environment for that pipeline stage. If the status is Rejected, the pipeline status is set to Rejected and the pipeline will end.

Figure 7 highlights the key steps that occur within the Lambda function that evaluates the Amazon Inspector scan status message.

Figure 7: Amazon Inspector scan results decision

Figure 7: Amazon Inspector scan results decision

Image deployment stage

If the container image is approved, the final image is deployed to an Amazon ECS cluster. The deploy stage of the pipeline is configured with Amazon ECS as the action provider. The deploy action contains the name of the Amazon ECS cluster and stage that the container image should be deployed to. The image definition file (imagedefinitions.json) that was created in the build stage is also listed in the deploy configuration. When the deploy stage runs, it will create a revision to the existing Amazon ECS task definition. This task definition contains the name of the Amazon ECR image that has been approved for deployment. The task definition is then deployed to the Amazon ECS cluster and service.

Deploy the solution

Now that you have an understanding of how the container pipeline solution works, you can deploy the solution to your own AWS account. This section will walk you through the steps to deploy the container approval pipeline, and show you how to verify that each of the key steps is working.

Step 1: Activate Amazon Inspector in your AWS account

The sample solution provided by this blog post requires that you activate Amazon Inspector in your AWS account. If this service is not activated in your account, learn more about the free trial and pricing for this service, and follow the steps in Getting started with Amazon Inspector to set up the service and start monitoring your account.

Step 2: Deploy the AWS CloudFormation template

For this next step, make sure you deploy the template within the AWS account and AWS Region where you want to test this solution.

To deploy the CloudFormation stack

  1. Choose the following Launch Stack button to launch a CloudFormation stack in your account. Use the AWS Management Console navigation bar to choose the region you want to deploy the stack in.

    Select this image to open a link that starts building the CloudFormation stack

  2. Review the stack name and the parameters for the template. The parameters are pre-populated with the necessary values, and there is no need to change them.
  3. Scroll to the bottom of the Quick create stack screen and select the checkbox next to I acknowledge that AWS CloudFormation might create IAM resources.
  4. Choose Create stack. The deployment of this CloudFormation stack will take 3–5 minutes.

After the CloudFormation stack has deployed successfully, you can proceed to reviewing and interacting with the deployed solution.

Step 3: Review the container pipeline and supporting resources

The CloudFormation stack is designed to deploy a collection of resources that will be used for an initial container build. When the CodePipeline resource is created, it will automatically pull the assets from the CodeCommit repository and start the pipeline for the container image.

To review the pipeline and resources

  1. In the CodePipeline console, navigate to the Region that the stack was deployed in.
  2. Choose the pipeline named ContainerBuildDeployPipeline to show the full pipeline details.
  3. Review the Source and Build stage, which will show a status of Succeeded.
  4. Review the ContainerVulnerabilityAssessment stage, which will show as failed with a Rejected status in the Manual Approval step.

    Figure 8 shows the full completed pipeline.

    Figure 8: Rejected container pipeline

    Figure 8: Rejected container pipeline

  5. Choose the Details link in the Manual Approval stage to reveal the reasons for the rejection. An example review summary is shown in Figure 9.
    Figure 9: Container pipeline approval rejection

    Figure 9: Container pipeline approval rejection

Review findings in Amazon Inspector (Optional)

You can use the Amazon Inspector console to see the full findings detail for this container image, if needed.

To view the findings in Amazon Inspector

  1. In the Amazon Inspector console, under Findings, choose By repository.
  2. From the list of repositories, choose the inspector-blog-images repository.
  3. Choose the Image tag link to bring up a list of the individual vulnerabilities that were found within the container image. Figure 10 shows an example of the vulnerabilities list in the findings details.
    Figure 10: Container image findings in Amazon Inspector

    Figure 10: Container image findings in Amazon Inspector

Step 4: Adjust the Amazon ECS desired count for the cluster service

Up to this point, you’ve deployed a pipeline to build and validate the container image, and you’ve seen an example of how the pipeline handles a container image that did not meet the defined vulnerability thresholds. Now you’ll deploy a new container image that will pass a vulnerability assessment and complete the pipeline.

The Amazon ECS service that the CloudFormation template deploys is initially created with the number of desired tasks set to 0. In order to allow the container pipeline to successfully deploy a container, you need to update the desired tasks value.

To adjust the task count in Amazon ECS (console)

  1. In the Amazon ECS console, choose the link for the cluster, in this case InspectorBlogCluster.
  2. On the Services tab, choose the link for the service named InspectorBlogService.
  3. Choose the Update button. On the Configure service page, set Number of tasks to 1.
  4. Choose Skip to review, and then choose Update Service.

To adjust the task count in Amazon ECS (AWS CLI)

Alternatively, you can run the following AWS CLI command to update the desired task count to 1. In order to run this command, you need the ARN of the Amazon ECS cluster, which you can retrieve from the Output tab of the CloudFormation stack that you created. You can run this command from the command line of an environment of your choosing, or by using AWS CloudShell. Make sure to replace <Cluster ARN> with your own value.

$ aws ecs update-service --cluster <Cluster ARN> --service InspectorBlogService --desired-count 1

Step 5: Build and deploy a new container image

Deploying a new container image will involve pushing an updated Dockerfile to the ContainerComponentsRepo repository in CodeCommit. With CodeCommit you can interact by using standard Git commands from a command line prompt, and there are multiple approaches that you can take to connect to the AWS CodeCommit repository from the command line. For this post, in order to simplify the interactions with CodeCommit, you will be shown how to add an updated file directly through the CodeCommit console.

To add an updated Dockerfile to CodeCommit

  1. In the CodeCommit console, choose the repository named ContainerComponentsRepo.
  2. In the screen listing the repository files, choose the Dockerfile file link and choose Edit.
  3. In the Edit a file form, overwrite the existing file contents with the following command:
    FROM public.ecr.aws/amazonlinux/amazonlinux:latest
  4. In the Commit changes to main section, fill in the following fields.
    1. Author name: your name
    2. Email address: your email
    3. Commit message: ‘Updated Dockerfile’

    Figure 11 shows what the completed form should look like.

    Figure 11: Complete CodeCommit entry for an updated Dockerfile

    Figure 11: Complete CodeCommit entry for an updated Dockerfile

  5. Choose Commit changes to save the new Dockerfile.

This update to the Dockerfile will immediately invoke a new instance of the container pipeline, where the updated container image will be pulled and evaluated by Amazon Inspector.

Step 6: Verify the container image approval and deployment

With a new pipeline initiated through the push of the updated Dockerfile, you can now review the overall pipeline to see that the container image was approved and deployed.

To see the full details in CodePipeline

  1. In the CodePipeline console, choose the container-build-deploy pipeline. You should see the container pipeline in an active status. In about five minutes, you should see the ContainerVulnerabilityAssessment stage move to completed with an Approved status, and the deploy stage should show a Succeeded status.
  2. To confirm that the final image was deployed to the Amazon ECS cluster, from the Deploy stage, choose Details. This will open a new browser tab for the Amazon ECS service.
  3. In the Amazon ECS console, choose the Tasks tab. You should see a task with Last status showing RUNNING. This is confirmation that the image was successfully approved and deployed through the container pipeline. Figure 12 shows where the task definition and status are located.
    Figure 12: Task status after deploying the container image

    Figure 12: Task status after deploying the container image

  4. Choose the task definition to bring up the latest task definition revision, which was created by the deploy stage of the container pipeline.
  5. Scroll down in the task definition screen to the Container definitions section. Note that the task is tied to the image you deployed, providing further verification that the approved container image was successfully deployed. Figure 13 shows where the container definition can be found and what you should expect to see.
    Figure 13: Container associated with revised task definition

    Figure 13: Container associated with revised task definition

Clean up the solution

When you’re finished deploying and testing the solution, use the following steps to remove the solution stack from your account.

To delete images from the Amazon ECR repository

  1. In the Amazon ECR console, navigate to the AWS account and Region where you deployed the solution.
  2. Choose the link for the repository named inspector-blog-images.
  3. Delete all of the images that are listed in the repository.

To delete objects in the CodePipeline artifact bucket

  1. In the Amazon S3 console in your AWS account, locate the bucket whose name starts with blog-base-setup-codepipelineartifactstorebucket.
  2. Delete the ContainerBuildDeploy folder that is in the bucket.

To delete the CloudFormation stack

  • In the CloudFormation console, delete the CloudFormation stack that was created to perform the steps in this post.

Conclusion

This post describes a solution that allows you to build your container images, have the images scanned for vulnerabilities by Amazon Inspector, and use the output from Amazon Inspector to determine whether the image should be allowed to be deployed into your environments.

This solution represents a pipeline with very simple build and deploy stages. Your pipeline will vary and may consist of multiple test stages and deployment stages for multiple environments. Additionally, the logic you use to determine whether a container image should be deployed may be different. The contents of this blog post are intended to help serve as a foundation that you can build on as you decide how to use Amazon Inspector for container vulnerability scanning. Feel free to use this guidance, and the example we provided, to extend the solution into your specific deployment pipeline.

 
If you have questions, contact AWS Support, or start a new thread on the AWS re:Post Amazon Inspector Forum. If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Scott Ward

Scott Ward

Scott is a Principal Solutions Architect with the External Security Services (ESS) product team and has been with Amazon for over 20 years. Scott provides technical guidance to customers on how to use security services to protect their AWS environments. Past roles included technical lead for the AWS security partner segment and member of the technical team for Amazon.com’s global financial systems.

Create a Multi-Region Python Package Publishing Pipeline with AWS CDK and CodePipeline

Post Syndicated from Brian Smitches original https://aws.amazon.com/blogs/devops/create-a-multi-region-python-package-publishing-pipeline-with-aws-cdk-and-codepipeline/

Customers can author and store internal software packages in AWS by leveraging the AWS CodeSuite (AWS CodePipeline, AWS CodeBuild, AWS CodeCommit, and AWS CodeArtifact).  As of the publish date of this blog post, there is no native way to replicate your CodeArtifact Packages across regions. This blog addresses how a custom solution built with the AWS Cloud Development Kit and AWS CodePipeline can create a Multi-Region Python Package Publishing Pipeline.

Whether it’s for resiliency or performance improvement, many customers want to deploy their applications across multiple regions. When applications are dependent on custom software packages, the software packages should be replicated to multiple regions as well. This post will walk through how to deploy a custom package publishing pipeline in your own AWS Account. This pipeline connects a Python package source code repository to build and publish pip packages to CodeArtifact Repositories spanning three regions (the primary and two replica regions). While this sample CDK Application is built specifically for pip packages, the underlying architecture can be reused for different software package formats, such as npm, Maven, NuGet, etc.

Solution overview

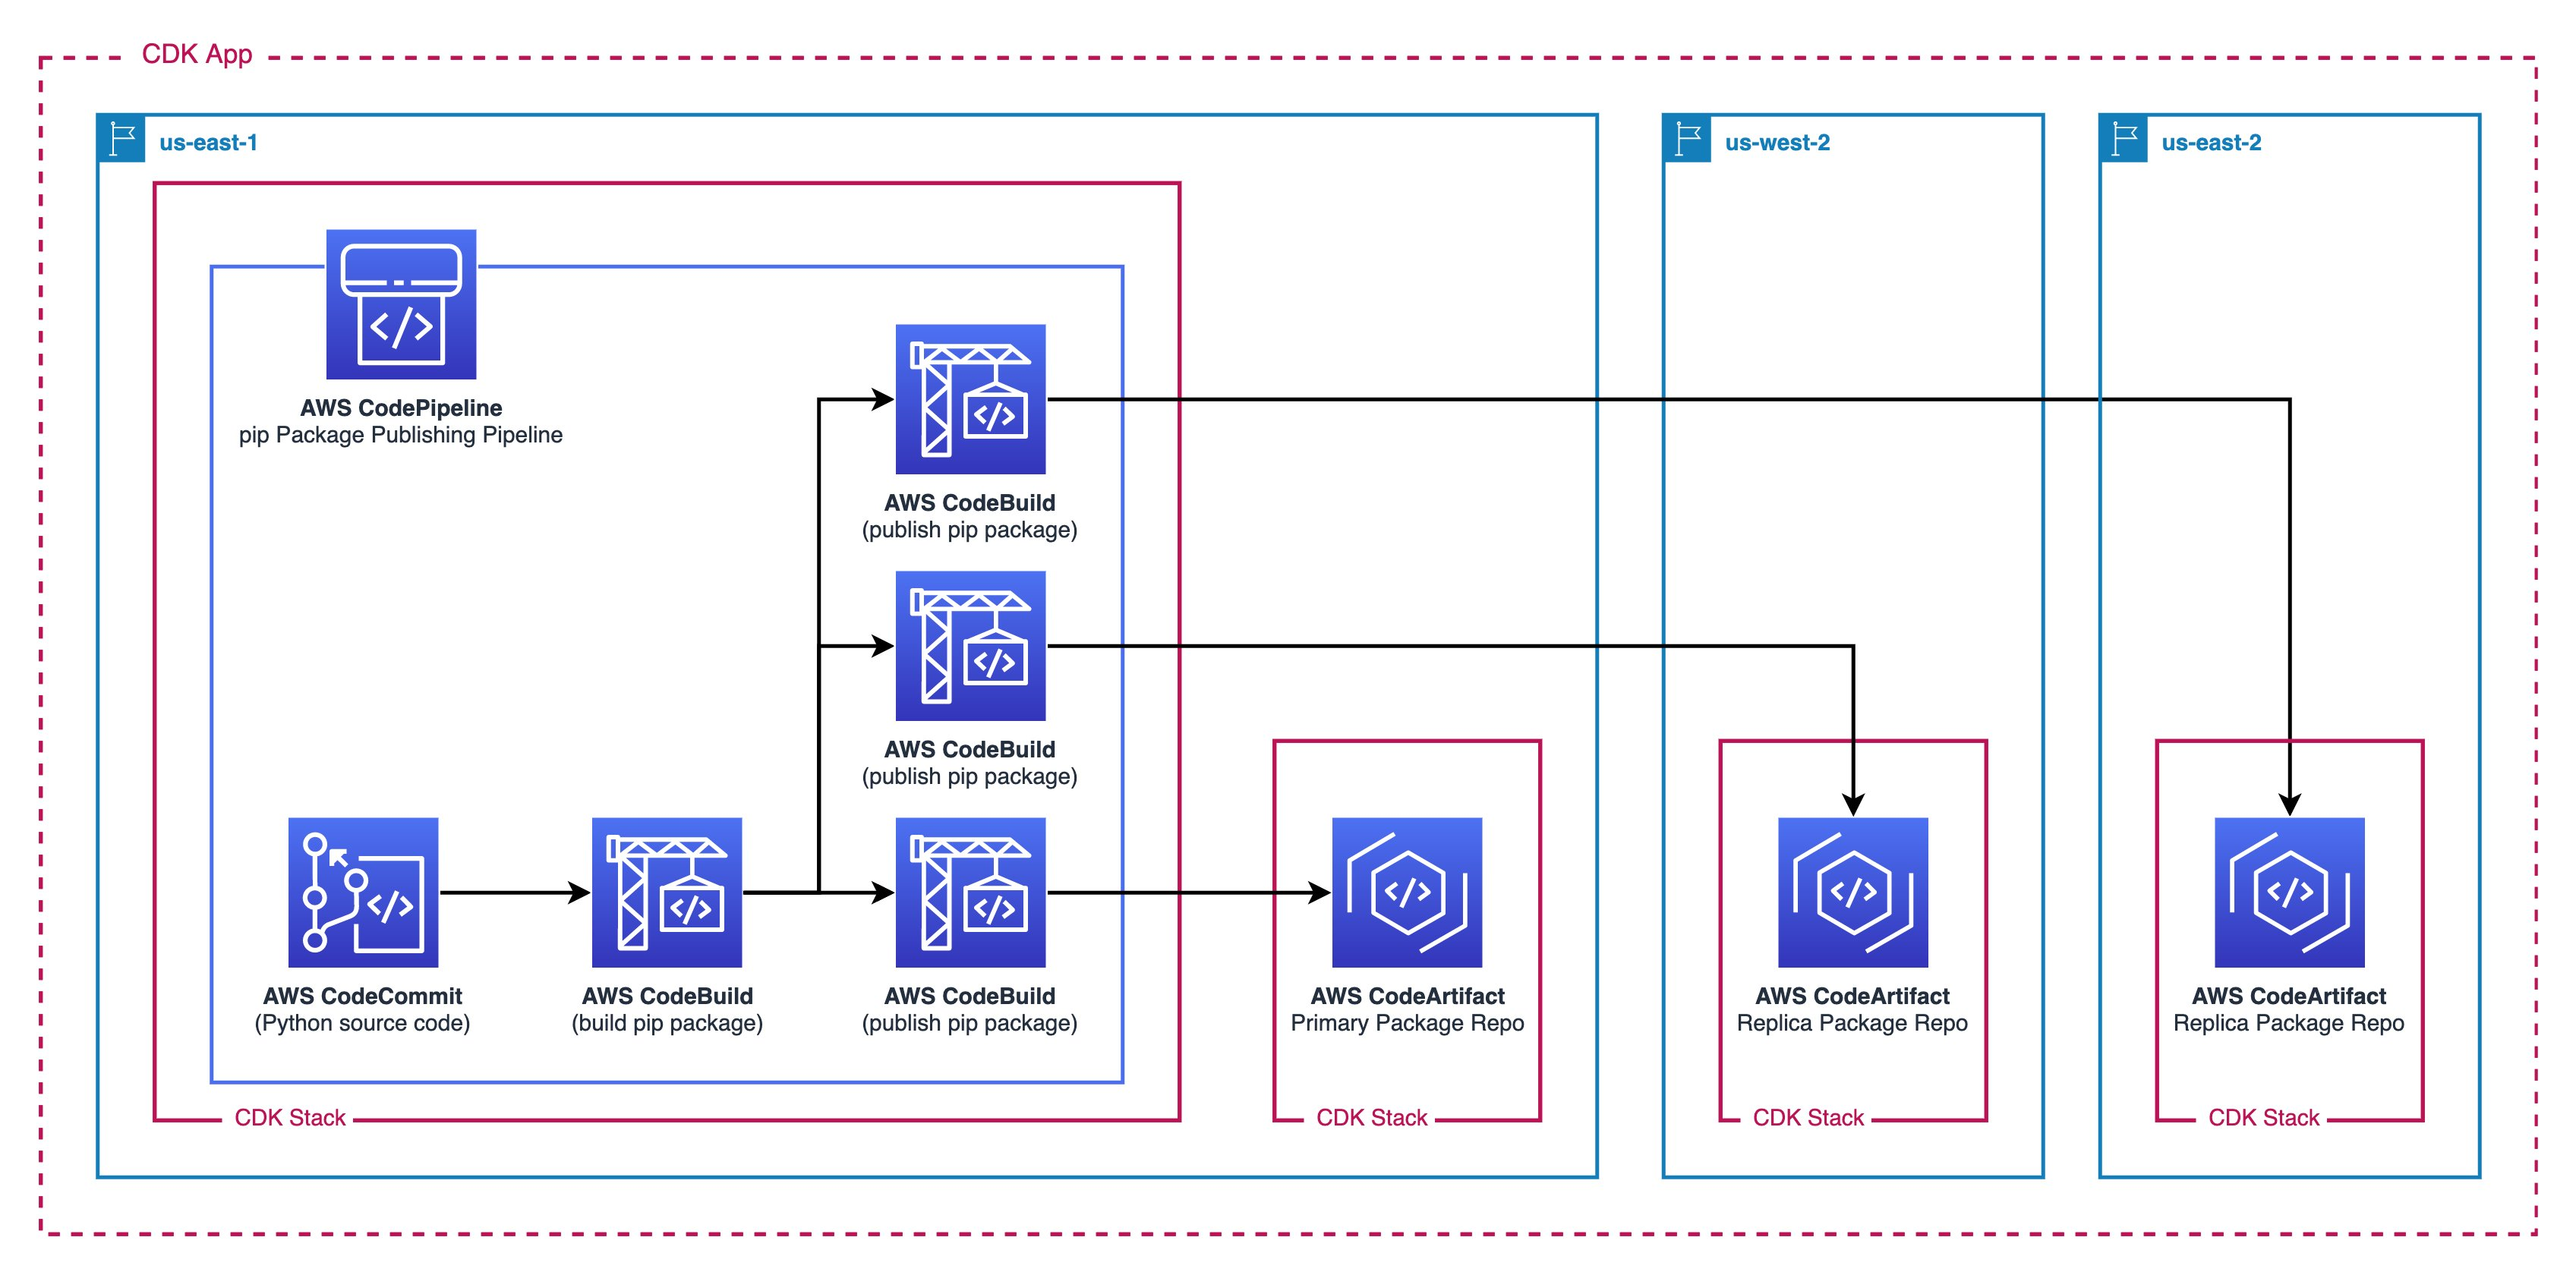
The following figure demonstrates the solution workflow:

  1. A CodePipeline pipeline orchestrates the building and publishing of the software package
    1. This pipeline is triggered by commits on the main branch of the CodeCommit repository
    2. A CodeBuild job builds the pip packages using twine to be distributed
    3. The publish stage (third column) uses three parallel CodeBuild jobs to publish the distribution package to the two CodeArtifact repositories in separate regions
  1. The first CodeArtifact Repository stores the package contents in the primary region.
  2. The second and third CodeArtifact Repository act as replicas and store the package contents in other regions.
Figure 1. A figure showing the architecture diagram

Figure 1.  Architecture diagram

All of these resources are defined in a single AWS CDK Application. The resources are defined in CDK Stacks that are deployed as AWS CloudFormation Stacks. AWS CDK can deploy the different stacks across separate regions.

Prerequisites

Before getting started, you will need the following:

  1. An AWS account
  2. An instance of the AWS Cloud9 IDE or an alternative local compute environment, such as your personal computer
  3. The following installed on your compute environment:
    1. AWS CDK
    2. AWS Command Line Interface (AWS CLI)
    3. npm
  1. The AWS Accounts must be bootstrapped for CDK in the necessary regions. The default configuration uses us-east-1, us-east-2 and us-west-2  as these three regions support CodeArtifact.

A new AWS Cloud9 IDE is recommended for this tutorial to isolate these actions in this post from your normal compute environment. See the Cloud9 Documentation for Creating an Environment.

Deploy the Python Package Publishing Pipeline into your AWS Account with the CDK

The source code can be found in this GitHub Repository.

  1. Fork the GitHub Repo into your account. This way you can experiment with changes as necessary to fit your workload.
  2. In your local compute environment, clone the GitHub Repository and cd into the project directory:
git clone [email protected]:<YOUR_GITHUB_USERNAME>/multi-region-
python-package-publishing-pipeline.git && cd multi-region-
python-package-publishing-pipeline
  1. Install the necessary node packages:
npm i
  1. (Optional) Override the default configurations for the CodeArtifact domainName, repositoryName, primaryRegion, and replicaRegions.
    1. navigate to ./bin/multiregion_package_publishing.ts and update the relevant fields.
    2. From the project’s root directory (multi-region-python-package-publishing-pipeline), deploy the AWS CDK application. This step may take 5-10 minutes.
cdk deploy --all
  1. When prompted “Do you wish to deploy these changes (y/n)?”, Enter y.

Viewing the deployed CloudFormation stacks

After the deployment of the AWS CDK application completes, you can view the deployed AWS CDK Stacks via CloudFormation. From the AWS Console, search “CloudFormation’ in the search bar and navigate to the service dashboard. In the primary region (us-east-1(N. Virginia)) you should see two stacks: CodeArtifactPrimaryStack-<region> and PackagePublishingPipelineStack.

Screenshot showing the CloudFormation Stacks in the primary region

Figure 2. Screenshot showing the CloudFormation Stacks in the primary region

Switch regions to one of the secondary regions us-west-2 (Oregon) or us-east-2 (Ohio) to see the remaining stacks named CodeArtifactReplicaStack-<region>. These correspond to the three AWS CDK Stacks from the architecture diagram.

Screenshot showing the CloudFormation stacks in a separate region

Figure 3. Screenshot showing the CloudFormation stacks in a separate region

Viewing the CodePipeline Package Publishing Pipeline

From the Console, select the primary region (us-east-1) and navigate to CodePipeline by utilizing the search bar. Select the Pipeline titled packagePipeline and inspect the state of the pipeline. This pipeline triggers after every commit from the CodeCommit repository named PackageSourceCode. If the pipeline is still in process, then wait a few minutes, as this pipeline can take approximately 7–8 minutes to complete all three stages (Source, Build, and Publish). Once it’s complete, the pipeline should reflect the following screenshot:

A screenshot showing the CodePipeline flow

Figure 4. A screenshot showing the CodePipeline flow

Viewing the Published Package in the CodeArtifact Repository

To view the published artifacts, go to the primary or secondary region and navigate to the CodeArtifact dashboard by utilizing the search bar in the Console. You’ll see a repository named package-artifact-repo. Select the repository and you’ll see the sample pip package named mypippackage inside the repository. This package is defined by the source code in the CodeCommit repository named PackageSourceCode in the primary region (us-east-1).

Screenshot of the package repository

Figure 5. Screenshot of the package repository

Create a new package version in CodeCommit and monitor the pipeline release

Navigate to your CodeCommit’s PackageSourceCode (us-east-1 CodeCommit > Repositories > PackageSourceCode. Open the setup.py file and select the Edit button. Make a simple modification, change the version = '1.0.0' to version = '1.1.0' and commit the changes to the Main branch.

A screenshot of the source package's code repository in CodeCommit

Figure 6. A screenshot of the source package’s code repository in CodeCommit

Now navigate back to CodePipeline and watch as the pipeline performs the release automatically. When the pipeline finishes, this new package version will live in each of the three CodeArtifact Repositories.

Install the custom pip package to your local Python Environment

For your development team to connect to this CodeArtifact Repository to download repositories, you must configure the pip tool to look in this repository. From your Cloud9 IDE (or local development environment), let’s test the installation of this package for Python3:

  1. Copy the connection instructions for the pip tool. Navigate to the CodeArtifact repository of your choice and select View connection instructions
    1. Select Copy to copy the snippet to your clipboard
Screenshot showing directions to connect to a code artifact repository

Figure 7. Screenshot showing directions to connect to a code artifact repository

  1. Paste the command from your clipboard
  2. Run pip install mypippackage==1.0.0
Screenshot showing CodeArtifact login

Figure 8. Screenshot showing CodeArtifact login

  1. Test the package works as expected by importing the modules
  2. Start the Python REPL by running python3 in the terminal
Screenshot of the package being imported

Figure 9. Screenshot of the package being imported

Clean up

Destroy all of the AWS CDK Stacks by running cdk destroy --all from the root AWS CDK application directory.

Conclusion

In this post, we walked through how to deploy a CodePipeline pipeline to automate the publishing of Python packages to multiple CodeArtifact repositories in separate regions. Leveraging the AWS CDK simplifies the maintenance and configuration of this multi-region solution by using Infrastructure as Code and predefined Constructs. If you would like to customize this solution to better fit your needs, please read more about the AWS CDK and AWS Developer Tools. Some links we suggest include the CodeArtifact User Guide (with sections covering npm, Python, Maven, and NuGet), the CDK API Reference, CDK Pipelines, and the CodePipeline User Guide.

About the authors:

Andrew Chen

Andrew Chen is a Solutions Architect with an interest in Data Analytics, Machine Learning, and DevOps. Andrew has previous experience in management consulting in which he worked as a technical architect for various cloud migration projects. In his free time, Andrew enjoys fishing, hiking, kayaking, and keeping up with financial markets.

Brian Smitches

Brian Smitches is a Solutions Architect with an interest in Infrastructure as Code and the AWS Cloud Development Kit. Brian currently supports Federal SMB Partners and has previous experience with Full Stack Application Development. In his personal time, Brian enjoys skiing, water sports, and traveling with friends and family.

How to control non-HTTP and non-HTTPS traffic to a DNS domain with AWS Network Firewall and AWS Lambda

Post Syndicated from Tyler Applebaum original https://aws.amazon.com/blogs/security/how-to-control-non-http-and-non-https-traffic-to-a-dns-domain-with-aws-network-firewall-and-aws-lambda/

Security and network administrators can control outbound access from a virtual private cloud (VPC) to specific destinations by using a service like AWS Network Firewall. You can use stateful rule groups to control outbound access to domains for HTTP and HTTPS by default in Network Firewall. In this post, we’ll walk you through how to accomplish this access control for non-HTTP and non-HTTPS traffic, such as SSH (Secure Shell). This solution is extensible to other protocols with static port assignments.

In the example scenario in this post, the network administrator needs to permit outbound SSH access on port 22/tcp to a third-party domain, example.org, from a group of Amazon Elastic Compute Cloud (Amazon EC2) instances that sits inside of a protected VPC that restricts outbound SSH traffic with Network Firewall. Non-HTTP traffic can’t currently be controlled with a domain rule in Network Firewall.

This solution allows administrators to control outbound access to a given domain in a granular way, by resolving the domain name inside of an AWS Lambda function, and updating a Network Firewall rule variable with the results of the DNS query. This solution further restricts specific non-HTTP and non-HTTPS traffic to those allowed domains to only what is explicitly specified by the administrator.

Solution overview

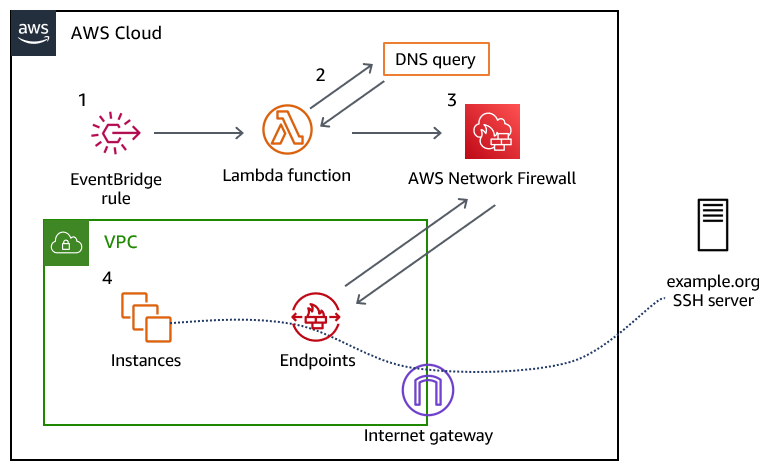
Figure 1 provides an overview of the solution and the resulting traffic flow.

Figure 1: Overview of the solution and the resulting traffic flow

Figure 1: Overview of the solution and the resulting traffic flow

The solution workflow is as follows:

  1. An Amazon EventBridge rule invokes the Lambda function every 10 minutes. You can modify this frequency to meet your needs. You should consider the time-to-live (TTL) record of the DNS record that you are configuring when choosing this interval.
  2. The Lambda function performs the DNS lookup for the provided domain, and updates a variable in an existing Network Firewall rule group. The rule group changes take a few seconds to fully apply to the nodes in your Network Firewall deployment.
  3. The newly created Network Firewall rule group is associated with the Network Firewall policy to control traffic.
  4. Traffic from the instances in your VPC flows through the Network Firewall endpoint, and if allowed, is routed through an internet gateway to the target server.

Prerequisites

This solution has the following prerequisites:

  1. An AWS account. If you don’t have an AWS account, create and activate one.
  2. An existing VPC with default routing to an internet gateway through a network firewall that has a firewall policy attached to it. The example rule included in the solution’s AWS CloudFormation template expects the firewall policy to use the default action order for stateful rule groups. If you don’t have an existing network firewall associated with your VPC, see the AWS Network Firewall Developer Guide to get started. For a walkthrough of the Network Firewall configuration and rules engine, see the blog post Hands-on walkthrough of the AWS Network Firewall flexible rules engine – Part 1.
  3. A DNS domain that you provide, which allows traffic for the protocol and port (or ports) that you plan to allow traffic to. This DNS domain needs to resolve to an IPv4 address or set of addresses; IPv6 is not supported, at this point.

Deploy the solution

We’ve provided a CloudFormation template to deploy this solution, which is located in the GitHub repository that accompanies this blog post.

To deploy the solution

  1. Download the CloudFormation template from our GitHub repository.
  2. Sign in to your AWS account and select the AWS Region where your Network Firewall is deployed.
  3. Navigate to the CloudFormation service.
  4. Choose Stacks > Create Stack > With new resources (standard).
  5. In the Specify template section, choose Upload a template file.
  6. Choose Choose file, navigate to where you saved the CloudFormation template, and upload it. Then choose Next.
  7. Specify a stack name for your CloudFormation stack.
  8. In the Parameters section, for the Domain parameter, specify the name of the domain to which you will control access. The default value is set to example.org; however, note that the actual example.org doesn’t allow SSH traffic.
  9. The remaining parameters have defaults to allow outbound SSH traffic to the specified domain. Adjust the LambdaJobFrequency variable so that it corresponds with the TTL of the DNS record that it will resolve. This allows the Lambda function to keep the IP address of the DNS record up to date, in the event that it changes. After you’ve configured the parameters, choose Next.
    Figure 2: CloudFormation stack parameters

    Figure 2: CloudFormation stack parameters

  10. On the Configure stack options page, specify any further options needed or keep the default options, and then choose Next.
  11. On the Review page, review the stack and parameters and select the check box to acknowledge that this template will create IAM resources. Choose Create Stack.
  12. Check the stack creation status. Upon successful completion, the status shows CREATE_COMPLETE.
    Figure 3: The successful creation of the CloudFormation stack

    Figure 3: The successful creation of the CloudFormation stack

Test the solution

Before you test the newly created rule, make sure that the Lambda function has been invoked at least once from the EventBridge rule.

To verify the Lambda function results

  1. In the AWS Management Console, navigate to the Lambda function Network-Firewall-Resolver-Function, and on the Monitor tab, choose View logs in CloudWatch.
    Figure 4: Navigating to view logs in CloudWatch

    Figure 4: Navigating to view logs in CloudWatch

  2. Select the most recent log stream.
  3. Verify that that a log line contains the entry StatefulRuleGroup updated successfully.
    Figure 5: Examining the CloudWatch logs to verify that the Lambda function ran successfully

    Figure 5: Examining the CloudWatch logs to verify that the Lambda function ran successfully

  4. Associate the stateful rule group that was created by the stack, Lambda-Managed-Stateful-Rule with the existing Network Firewall policy that is attached to your VPC. To do this:
    1. Navigate to VPC > Network Firewall > Firewall Policies and select your existing firewall policy.
    2. In the Stateful rule groups section, for Actions, choose Add unmanaged stateful rule groups.
  5. Select the check box for Lambda-Managed-Stateful-Rule, and then choose Add stateful rule group.
  6. When the newly provisioned Lambda function runs successfully, it will resolve the IPv4 address for the domain (example.org) and associate the address with the stateful rule variable IP_NET. To validate that this has happened, do the following:
    1. Navigate to VPC > Network Firewall > Network Firewall rule groups.
    2. Choose the Lambda-Managed-Stateful-Rule rule group.
    3. Navigate to the rule variable section, and choose IP_NET. If the Lambda function successfully resolved the provided domain name, the variable will contain the IPv4 addresses for the domain you provided, as shown in Figure 6.
      Figure 6: Validating the rule variable details

      Figure 6: Validating the rule variable details

  7. Test the rule by attempting to connect to the domain that you specified in the CloudFormation template. Use an EC2 instance within the VPC that the network firewall rule is associated with, and attempt to establish an SSH connection to the domain that you specified. As shown by the SSH key negotiation in Figure 7, traffic is allowed through the network firewall, as intended.
    Figure 7: SSH connectivity to the domain was successful

    Figure 7: SSH connectivity to the domain was successful

    You can also configure the rule to drop the SSH connection, rather than permit it. To do this:

    1. Navigate to VPC > Network Firewall > Network Firewall rule groups.
    2. Choose the Lambda-Managed-Stateful-Rule rule group. In the Rules section, choose Edit Rules.
    3. Modify the rule to take the Drop action, and save the rule group.

    As shown by the lack of response from the host in Figure 8, the SSH connection cannot be established anymore.

    Figure 8: An SSH connection cannot be established, due to the connection timing out

    Figure 8: An SSH connection cannot be established, due to the connection timing out

Cleanup

Follow the steps in this section to remove the resources created by this solution.

To remove the resources

  1. Sign in to your AWS account where you deployed the CloudFormation stack and navigate to the Network Firewall console.
  2. In the Stateful rule groups section, select the check box for Lambda-Managed-Stateful-Rule. For Actions, choose Disassociate from policy.
    Figure 9: Disassociating the stateful rule from the existing policy

    Figure 9: Disassociating the stateful rule from the existing policy

  3. Navigate to the CloudFormation console, select the stack that you created, and then choose Delete. Upon successful deletion, the resources created by the stack will be deleted.

Conclusion

In this post, we’ve demonstrated how security and network administrators have the ability to permit or restrict non-HTTP and non-HTTPS traffic to a given domain by using Network Firewall. With this solution, administrators can enforce granular port- and protocol-level control to third-party domains. To learn more about rule group configuration in AWS Network Firewall, see Managing your own rule groups in the Developer Guide.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support. You can also start a new thread on AWS Network Firewall re:Post to get answers from the community.

Want more AWS Security news? Follow us on Twitter.

Tyler Applebaum

Tyler Applebaum

Tyler is a Sr. Solutions Architect in the Charlotte, NC area helping customers migrate to AWS and modernize their applications. He has previous experience as a network engineer working in healthcare and finance.

Bhavin Lakhani

Bhavin is a Technical Account Manager in the US West, Northern California, helping customers with their AWS Enterprise Support, Operational, and Architectural needs. He has cloud infrastructure and database platform leadership experience in his previous roles. He loves soccer and is an ardent “Arsenal” fan.

Microservice observability with Amazon OpenSearch Service part 2: Create an operational panel and incident report

Post Syndicated from Marvin Gersho original https://aws.amazon.com/blogs/big-data/microservice-observability-with-amazon-opensearch-service-part-2-create-an-operational-panel-and-incident-report/

In the first post in our series , we discussed setting up a microservice observability architecture and application troubleshooting steps using log and trace correlation with Amazon OpenSearch Service. In this post, we discuss using PPL to create visualizations in operational panels, and creating a simple incident report using notebooks.

To try out the solution yourself, start from part 1 of the series.

Microservice observability with Amazon OpenSearch Service

Piped Processing Language (PPL)

PPL is a new query language for OpenSearch. It’s simpler and more straightforward to use than query DSL (Domain Specific Language), and a better fit for DevOps than ODFE SQL. PPL handles semi-structured data and uses a sequence of commands delimited by pipes (|). For more information about PPL, refer to Using pipes to explore, discover and find data in Amazon OpenSearch Service with Piped Processing Language.

The following PPL query retrieves the same record as our search on the Discover page in our previous post. If you’re following along, use your trace ID in place of <Trace-ID>:

source = sample_app_logs | where stream = 'stderr' and locate(‘<Trace-ID>’,`log`) > 0

The query has the following components:

  • | separates commands in the statement.
  • Source=sample_app_logs means that we’re searching sample_app_logs.
  • where stream = ‘stderr’, stream is a field in sample_app_logs. We’re matching the value to stderr.
  • The locate function allows us to search for a string in a field. For our query, we search for the trace_id in the log field. The locate function returns 0 if the string is not found, otherwise the character number where it is found. We’re testing that trace_id is in the log field. This lets us find the entry that has the payment trace_id with the error.

Note that log is PPL keyword, but also a field in our log file. We put backquotes around a field name if it’s also a keyword if we need to reference it in a PPL statement.

To start using PPL, complete the following steps:

  1. On OpenSearch Dashboards, choose Observability in the navigation pane.
  2. Choose Event analytics.
  3. Choose the calendar icon, then choose the time period you want for your query (for this post, Year to date).
  4. Enter your PPL statement.

Note that results are shown in table format by default, but you can also choose to view them in JSON format.

Monitor your services using visualizations

We can use the PPL on the Event analytics page to create real-time visualizations. We now use these visualizations to create a dashboard for real-time monitoring of our microservices on the Operational panels page.

Event analytics has two modes: events and visualizations. With events, we’re looking at the query results as a table or JSON. With visualizations, the results are shown as a graph. For this post, we create a PPL query that monitors a value over time, and see the results in a graph. We can then save the graph to use in our dashboard. See the following code:

source = sample_app_logs | where stream = 'stderr' and locate('payment',`log`) > 0 | stats count() by span(time, 5m)

This code is similar to the PPL we used earlier, with two key differences:

  • We specify the name of our service in the log field (for this post, payment).
  • We use the aggregation function stats count() by span(time, 5m). We take the count of matches in the log field and aggregate by 5-minute intervals.

The following screenshot shows the visualization.

OpenSearch Service offers a choice of several different visualizations, such as line, bar, and pie charts.

We now save the results as a visualization, giving it the name Payment Service Errors.

We want to create and save a visualization for each of the five services. To create a new visualization, choose Add new, then modify the query by changing the service name.

We save this one and repeat the process by choosing Add new again for each of the five micro-services. Each microservice is now available on its own tab.

Create an operational panel

Operational panels in OpenSearch Dashboards are collections of visualizations created using PPL queries. Now that we have created the visualizations in the Event analytics dashboard, we can create a new operational panel.

  1. On the Operational panel page, choose Create panel.
  2. For Name, enter e-Commerce Error Monitoring.
  3. Open that panel and choose Add Visualization.
  4. Choose Payment Service Errors.

The following screenshot shows our visualization.

We now repeat the process for our other four services. However, the layout isn’t good. The graphs are too big, and laid out vertically, so they can’t all be seen at once.

We can choose Edit to adjust the size of each visualization and move them around. We end up with the layout in the following screenshot.

We can now monitor errors over time for all of our services. Notice that the y axis of each service visualization adjusts based on the error count.

This will be a useful tool for monitoring our services in the future.

Next, we create an incident report on the error that we found.

Create an OpenSearch incident report

The e-Commerce Error Monitoring panel can help us monitor our application in the future. However, we want to send out an incident report to our developers about our current findings. We do this by using OpenSearch PPL and Notebooks features introduced in OpenSearch Service 1.3 to create an incident report. A notebook can be downloaded as a PDF. An incident report is useful to share our findings with others.

First, we need to create a new notebook.

  1. Under Observability in the navigation pane, choose Notebooks.
  2. Choose Create notebook.
  3. For Name, enter e-Commerce Error Report.
  4. Choose Create.

    The following screenshot shows our new notebook page.

    A notebook consists of code blocks: narrative, PPL, and SQL, and visualizations created on the Event analytics page with PPL.
  5. Choose Add code block.
    We can now write a new code block.

    We can use %md, %sql, or %ppl to add code. In this first block, we just enter text.
  6. Use %md to add narrative text.
  7. Choose Run to see the output.

    The following screenshot shows our code block.

    Now we want to add our PPL query to show the error we found earlier.
  8. On the Add paragraph menu, choose Code block.
  9. Enter our PPL query, then choose Run.

    The following screenshot shows our output.

    Let’s drill down on the log field to get details of the error.
    We could have many narrative and code blocks, as well as visualizations of PPL queries. Let’s add a visualization.
  10. On the Add paragraph menu, choose Visualization.
  11. Choose Payment Service Errors to view the report we created earlier.

    This visualization shows a pattern of payment service errors this afternoon. Note that we chose a date range because we’re focusing on today’s errors to communicate with the development team.

    Notebook visualizations can be refreshed to provide updated information. The following screenshot shows our visualization an hour later.
    We’re now going to take our completed notebook and export it as a PDF report to share with other teams.
  12. Choose Output only to make the view cleaner to share.
  13. On the Reporting actions menu, choose Download PDF.

We can send this PDF report to the developers supporting the payment service.

Summary

In this post, we used OpenSearch Service v1.3 to create a dashboard to monitor errors in our microservices application. We then created a notebook to use a PPL query on a specific trace ID for a payment service error to provide details, and a graph of payment service errors to visualize the pattern of errors. Finally, we saved our notebook as a PDF to share with the payment service development team. If you would like to explore these features further check out the latest Amazon OpenSearch Observability documentation or, for open source, OpenSearch Observability latest open source documentation. You can also contact your AWS Solutions Architects, who can be of assistance alongside your innovation journey.


About the Authors

Marvin Gersho is a Senior Solutions Architect at AWS based in New York City. He works with a wide range of startup customers. He previously worked for many years in engineering leadership and hands-on application development, and now focuses on helping customers architect secure and scalable workloads on AWS with a minimum of operational overhead. In his free time, Marvin enjoys cycling and strategy board games.

Subham Rakshit is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

Rafael Gumiero is a Senior Analytics Specialist Solutions Architect at AWS. An open-source and distributed systems enthusiast, he provides guidance to customers who develop their solutions with AWS Analytics services, helping them optimize the value of their solutions.

Export historical Security Hub findings to an S3 bucket to enable complex analytics

Post Syndicated from Jonathan Nguyen original https://aws.amazon.com/blogs/security/export-historical-security-hub-findings-to-an-s3-bucket-to-enable-complex-analytics/

AWS Security Hub is a cloud security posture management service that you can use to perform security best practice checks, aggregate alerts, and automate remediation. Security Hub has out-of-the-box integrations with many AWS services and over 60 partner products. Security Hub centralizes findings across your AWS accounts and supported AWS Regions into a single delegated administrator account in your aggregation Region of choice, creating a single pane of glass to consolidate and view individual security findings.

Because there are a large number of possible integrations across accounts and Regions, your delegated administrator account in the aggregation Region might have hundreds of thousands of Security Hub findings. To perform complex analytics or machine learning across the existing (historical) findings that are maintained in Security Hub, you can export findings to an Amazon Simple Storage Service (Amazon S3) bucket. To export new findings that have recently been created, you can implement the solution in the aws-security-hub-findings-export GitHub repository. However, Security Hub has data export API rate quotas, which can make exporting a large number of findings challenging.

In this blog post, we provide an example solution to export your historical Security Hub findings to an S3 bucket in your account, even if you have a large number of findings. We walk you through the components of the solution and show you how to use the solution after deployment.

Prerequisites

To deploy the solution, complete the following prerequisites:

  1. Enable Security Hub.
  2. If you want to export Security Hub findings for multiple accounts, designate a Security Hub administrator account.
  3. If you want to export Security Hub findings across multiple Regions, enable cross-Region aggregation.

Solution overview and architecture

In this solution, you use the following AWS services and features:

  • Security Hub export orchestration
    • AWS Step Functions helps you orchestrate automation and long-running jobs, which are integral to this solution. You need the ability to run a workflow for hours due to the Security Hub API rate limits and number of findings and objects.
    • AWS Lambda functions handle the logic for exporting and storing findings in an efficient and cost-effective manner. You can customize Lambda functions to most use cases.
  • Storage of exported findings
  • Job status tracking
    • Amazon EventBridge tracks changes in the status of the Step Functions workflow. The solution can run for over 100 hours; by using EventBridge, you don’t have to manually check the status.
    • Amazon Simple Notification Service (Amazon SNS) sends you notifications when the long-running jobs are complete or when they might have issues.
    • AWS Systems Manager Parameter Store provides a quick way to track overall status by maintaining a numeric count of successfully exported findings that you can compare with the number of findings shown in the Security Hub dashboard.

Figure 1 shows the architecture for the solution, deployed in the Security Hub delegated administrator account in the aggregation Region. The figure shows multiple Security Hub member accounts to illustrate how you can export findings for an entire AWS Organizations organization from a single delegated administrator account.

Figure 1: High-level overview of process and resources deployed in the Security Hub account

Figure 1: High-level overview of process and resources deployed in the Security Hub account

As shown in Figure 1, the workflow after deployment is as follows:

  1. The Step Functions workflow for the Security Hub export is invoked.
  2. The Step Functions workflow invokes a single Lambda function that does the following:
    1. Retrieves Security Hub findings that have an Active status and puts them in a temporary file.
    2. Pushes the file as an object to Amazon S3.
    3. Adds the global count of exported findings from the Step Functions workflow to a Systems Manager parameter for validation and tracking purposes.
    4. Repeats steps b–c for about 10 minutes to get the most findings while preventing the Lambda function from timing out.
    5. If a nextToken is present, pushes the nextToken to the output of the Step Functions.

      Note: If the number of items in the output is smaller than the number of items returned by the API call, then the return output includes a nextToken, which can be passed to a subsequent command to retrieve the next set of items.

  3. The Step Functions workflow goes through a Choice state as follows:
    • If a Security Hub nextToken is present, Step Functions invokes the Lambda function again.
    • If a Security Hub nextToken isn’t present, Step Functions ends the workflow successfully.
  4. An EventBridge rule tracks changes in the status of the Step Functions workflow and sends events to an SNS topic. Subscribers to the SNS topic receive a notification when the status of the Step Functions workflow changes.

Deploy the solution

You can deploy the solution through either the AWS Management Console or the AWS Cloud Development Kit (AWS CDK).

To deploy the solution (console)

  • In your delegated administrator Security Hub account, launch the AWS CloudFormation template by choosing the following Launch Stack button. It will take about 10 minutes for the CloudFormation stack to complete.

    Launch Stack

    Note: The stack will launch in the US East (N. Virginia) Region (us-east-1). If you are using cross-Region aggregation, deploy the solution into the Region where Security Hub findings are consolidated. You can download the CloudFormation template for the solution, modify it, and deploy it to your selected Region.

To deploy the solution (AWS CDK)

  1. Download the code from our aws-security-hub-findings-historical-export GitHub repository, where you can also contribute to the sample code. The CDK initializes your environment and uploads the Lambda assets to Amazon S3. Then, you deploy the solution to your account.
  2. While you are authenticated in the security tooling account, run the following commands in your terminal. Make sure to replace <AWS_ACCOUNT> with the account number, and replace <REGION> with the AWS Region where you want to deploy the solution.
    cdk bootstrap aws://<AWS_ACCOUNT>/<REGION>
    cdk deploy SechubHistoricalPullStack

Solution walkthrough and validation

Now that you’ve successfully deployed the solution, you can see each aspect of the automation workflow in action.

Before you start the workflow, you need to subscribe to the SNS topic so that you’re notified of status changes within the Step Functions workflow. For this example, you will use email notification.

To subscribe to the SNS topic

  1. Open the Amazon SNS console.
  2. Go to Topics and choose the Security_Hub_Export_Status topic.
  3. Choose Create subscription.
  4. For Protocol, choose Email.
  5. For Endpoint, enter the email address where you want to receive notifications.
  6. Choose Create subscription.
  7. After you create the subscription, go to your email and confirm the subscription.

You’re now subscribed to the SNS topic, so any time that the Step Functions status changes, you will receive a notification. Let’s walk through how to run the export solution.

To run the export solution

  1. Open the Amazon Step Functions console.
  2. In the left navigation pane, choose State machines.
  3. Choose the new state machine named sec_hub_finding_export.
  4. Choose Start execution.
  5. On the Start execution page, for Name – optional and Input – optional, leave the default values and then choose Start execution.
    Figure 2: Example input values for execution of the Step Functions workflow

    Figure 2: Example input values for execution of the Step Functions workflow

  6. This will start the Step Functions workflow and redirect you to the Graph view. If successful, you will see that the overall Execution status and each step have a status of Successful.
  7. For long-running jobs, you can view the CloudWatch log group associated with the Lambda function to view the logs.
  8. To track the number of Security Hub findings that have been exported, open the Systems Manager console, choose Parameter Store, and then select the /sechubexport/findingcount parameter. Under Value, you will see the total number of Security Hub findings that have been exported, as shown in Figure 3.
    Figure 3: Systems Manager Parameter Store value for the number of Security Hub findings exported

    Figure 3: Systems Manager Parameter Store value for the number of Security Hub findings exported

Depending on the number of Security Hub findings, this process can take some time. This is primarily due to the GetFindings quota of 3 requests per second. Each GetFindings request can return a maximum of 100 findings, so this means that you can get up to 300 findings per second. On average, the solution can export about 1 million findings per hour. If you have a large number of findings, you can start the finding export process and wait for the SNS topic to notify you when the process is complete.

How to customize the solution

The solution provides a general framework to help you export your historical Security Hub findings. There are many ways that you can customize this solution based on your needs. The following are some enhancements that you can consider.

Change the Security Hub finding filter

The solution currently pulls all findings with RecordState: ACTIVE, which pulls the active Security Hub findings in the AWS account. You can update the Lambda function code, specifically the finding_filter JSON value within the create_filter function, to pull findings for your use case. For example, to get all active Security Hub findings from the AWS Foundational Security Best Practices standard, update the Lambda function code as follows.

{
                 WorkflowState: [
                     {
                         "Value": "NEW ",
                         "Comparison": "EQUALS"
                     },
                 ],
                 "RecordState": [
                     {
                         "Value": "ACTIVE",
                         "Comparison": "EQUALS"
                     },
                 ]
            }

Export more than 100 million Security Hub findings

The example solution can export about 100 million Security Hub findings. This number is primarily determined by the speed at which findings can be exported, due to the following factors:

If you want to export more than 100 million Security Hub findings, do one of the following:

Note: If you implement either of these solutions, make sure that the nextToken also gets passed to the new Step Functions execution by updating the Lambda function code to parse and pass the nextToken received in the last request.

Speed up the export

One way to increase the export bandwidth, and reduce the overall execution time, is to run the export job in parallel across the individual Security Hub member accounts rather than from the single delegated administrator account.

You could use CloudFormation StackSets to deploy this solution in each Security Hub member account and send the findings to a centralized S3 bucket. You would need to modify the solution to allow an S3 bucket to be provided as an input, and all the Lambda function Identity and Access Management (IAM) roles would need cross-account access to the S3 bucket and corresponding AWS Key Management Service (AWS KMS) key. You would also need to make updates in each member account to iterate through the various Regions in which the Security Hub findings exist.

Next steps

The solution in this post is designed to assist in the retrieval and export of all existing findings currently in Security Hub. After you successfully run this solution to export historical findings, you can continuously export new Security Hub findings by using the sample solution in the aws-security-hub-findings-export GitHub repository.

Now that you’ve exported the Security Hub findings, you can set up and run custom complex reporting or queries against the S3 bucket by using Amazon Athena and AWS Glue. Additionally, you can run machine learning and analytics capabilities by using services like Amazon SageMaker or Amazon Lookout for Metrics.

Conclusion

In this post, you deployed a solution to export the existing Security Hub findings in your account to a central S3 bucket, so that you can apply complex analytics and machine learning to those findings. We walked you through how to use the solution and apply it to some example use cases after you successfully exported existing findings across your AWS environment. Now your security team can use the data in the S3 bucket for predictive analytics and determine if there are Security Hub findings and specific resources that might need to be prioritized for review due to a deviation from normal behavior. Additionally, you can use this solution to enable more complex analytics on multiple fields by querying large and complex datasets with AWS Athena.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a thread on AWS Security Hub re:Post.

 
Want more AWS Security news? Follow us on Twitter.

Jonathan Nguyen

Jonathan Nguyen

Jonathan is a Shared Delivery Team Senior Security Consultant at AWS. His background is in AWS Security with a focus on threat detection and incident response. Today, he helps enterprise customers develop a comprehensive security strategy and deploy security solutions at scale, and he trains customers on AWS Security best practices.

Microservice observability with Amazon OpenSearch Service part 1: Trace and log correlation

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/part-1-microservice-observability-with-amazon-opensearch-service-trace-and-log-correlation/

Modern enterprises are increasingly adopting microservice architectures and moving away from monolithic structures. Although microservices provide agility in development and scalability, and encourage use of polyglot systems, they also add complexity. Troubleshooting distributed services is hard because the application behavioral data is distributed across multiple machines. Therefore, in order to have deep insights to troubleshoot distributed applications, operational teams need to collect application behavioral data in one place to scan through them.

Although setting up monitoring systems focuses on analyzing only log data can help you understand what went wrong and notify about any anomalies, it fails to provide insight into why something went wrong and exactly where in the application code it went wrong. Fixing issues in a complex network of systems is like finding a needle in a haystack. Observability based on Open Standards defined by OpenTelemetry addresses the problem by providing support to handle logs, traces, and metrics within a single implementation.

In this series, we cover the setup and troubleshooting of a distributed microservice application using logs and traces. Logs are immutable, timestamped, discreet events happening over a period of time, whereas traces are a series of related events that capture the end-to-end request flow in a distributed system. We look into how to collect a large volume of logs and traces in Amazon OpenSearch Service and correlate these logs and traces to find the actual issue and where the issue was generated.

Any investigation of issues in enterprise applications needs to be logged in an incident report, so that operational and development teams can collaborate to roll out a fix. When any investigation is carried out, it’s important to write a narrative about the issue so that it can be used in discussion later. We look into how to use the latest notebook feature in OpenSearch Service to create the incident report.

In this post, we discuss the architecture and application troubleshooting steps.

Solution overview

The following diagram illustrates the observability solution architecture to capture logs and traces.

The solution components are as follows:

  • Amazon OpenSearch Service is a managed AWS service that makes it easy to deploy, operate, and scale OpenSearch clusters in the AWS Cloud. OpenSearch Service supports OpenSearch and legacy Elasticsearch open-source software (up to 7.10, the final open-source version of the software).
  • FluentBit is an open-source processor and forwarder that collects, enriches, and sends metrics and logs to various destinations.
  • AWS Distro for OpenTelemetry is a secure, production-ready, AWS-supported distribution of the OpenTelemetry project. With AWS Distro for OpenTelemetry, you can instrument your applications just once to send correlated metrics and traces to multiple AWS and Partner monitoring solutions, including OpenSearch Service.
  • Data Prepper is an open-source utility service with the ability to filter, enrich, transform, normalize, and aggregate data to enable an end-to-end analysis lifecycle, from gathering raw logs to facilitating sophisticated and actionable interactive ad hoc analyses on the data.
  • We use a sample observability shop web application built as a microservice to demonstrate the capabilities of the solution components.
  • Amazon Elastic Kubernetes Service (Amazon EKS) is a managed service that you can use to run Kubernetes on AWS without needing to install, operate, and maintain your own Kubernetes control plane or nodes. Kubernetes is an open-source system for automating the deployment, scaling, and management of the container.

In this solution, we have a sample o11y (Observability) Shop web application written in Python and Java, and deployed in an EKS cluster. The web application is composed of various services. When some operations are done from the front end, the request travels through multiple services on the backend. The application services are running as separate containers, while AWS Distro for OpenTelemetry, FluentBit, and Data Prepper are running as sidecar containers.

FluentBit is used for collecting log data from application containers, and then sends logs to Data Prepper. For collecting traces, first the application services are instrumented using the OpenTelemetry SDK. Then, with AWS Distro for OpenTelemetry collector, trace information is collected and sent to Data Prepper. Data Prepper forwards the logs and traces data to OpenSearch Service.

We recommend deploying the OpenSearch Service domain within a VPC, so a reverse proxy is needed to be able to log in to OpenSearch Dashboards.

Prerequisite

You need an AWS account with necessary permissions to deploy the solution.

Set up the environment

We use AWS CloudFormation to provision the components of our architecture. Complete the following steps:

  1. Launch the CloudFormation stack in the us-east-1 Region:
  2. You may keep the stack name default to AOS-Observability.
  3. You may change the OpenSearchMasterUserName parameter used for OpenSearch Service login while keeping other parameter values to default. The stack provisions a VPC, subnets, security groups, route tables, an AWS Cloud9 instance, and an OpenSearch Service domain, along with a Nginx reverse proxy. It also configures AWS Identity and Access Management (IAM) roles. The stack will also generate a new random password for OpenSearch Service domain which can be seen in the CloudFormation Outputs tab under AOSDomainPassword.
  4. On the stack’s Outputs tab, choose the link for the AWS Cloud9 IDE.
  5. Run the following code to install the required packages, configure the environment variables and provision the EKS cluster:
    curl -sSL https://raw.githubusercontent.com/aws-samples/observability-with-amazon-opensearch-blog/main/scripts/eks-setup.sh | bash -s <<CloudFormation Stack Name>>

    After the resources are deployed, it prints the hostname for the o11y Shop web application.

  6. Copy the hostname and enter it in the browser.

This opens the o11y Shop microservice application, as shown in the following screenshot.

Access the OpenSearch Dashboards

To access the OpenSearch Dashboards, complete the following steps:

  1. Choose the link for AOSDashboardsPublicIP from the CloudFormation stack outputs. Because the OpenSearch Service domain is deployed inside the VPC, we use an Nginx reverse proxy to forward the traffic to the OpenSearch Service domain. Because the OpenSearch Dashboards URL is signed using a self-signed certificate, you need to bypass the security exception. In production, a valid certificate is recommended for secure access.
  2. Assuming you’re using Google Chrome, while you are on this page, enter thisisunsafe.Google Chrome redirects you to the OpenSearch Service login page.
  3. Log in with the OpenSearch Service login details (found in the CloudFormation stack output: AOSDomainUserName and AOSDomainPassword).You’re presented with a dialog requesting you to add data for exploration.
  4. Select Explore on my own.
  5. When asked to select a tenant, leave the default options and choose Confirm.
  6. Open the Hamburger menu to explore the plugins within OpenSearch Dashboards.

This is the OpenSearch Dashboards user interface. We use it in the next steps to analyze, explore, fix, and find the root cause of the issue.

Logs and traces generation

Click around the o11y Shop application to simulate user actions. This will generate logs and some traces for the associated microservices stored in OpenSearch Service. You can do the process multiple times to generate more sample logs and traces data.

Create an index pattern

An index pattern selects the data to use and allows you to define properties of the fields. An index pattern can point to one or more indexes, data streams, or index aliases.

You need to create an index pattern to query the data through OpenSearch Dashboards.

  1. On OpenSearch Dashboards, choose Stack Management.
  2. Choose Index Patterns
  3. Choose Create index pattern.
  4. For Index pattern name, enter sample_app_logs. OpenSearch Dashboards also supports wildcards.
  5. Choose Next step.
  6. For Time field, choose time.
  7. Choose Create index pattern.
  8. Repeat these steps to create the index pattern otel-v1-apm-span* with event.time as the time field for discovering traces.

Search logs

Choose the menu icon and look for the Discover section in OpenSearch Dashboards. The Discover panel allows you to view and query logs. Check the log activity happening in the microservice application.

If you can’t see any data, increase the time range to something large (like the last hour). Alternatively, you can play around the o11y Shop application to generate recent logs and traces data.

Instrument applications to generate traces

Applications need to be instrumented to generate and send trace data downstream. There are two types of instrumentation:

  • Automatic – In automatic instrumentation, no application code change is required. It uses an agent that can capture trace data from the running application. It requires usage of the language-specific API and SDK, which takes the configuration provided through the code or environment and provides good coverage of endpoints and operations. It automatically determines the span start and end.
  • Manual – In manual instrumentation, developers need to add trace capture code to the application. This provides customization in terms of capturing traces for a custom code block, naming various components in OpenTelemetry like traces and spans, adding attributes and events, and handling specific exceptions within the code.

In our application code, we use manual instrumentation. Refer to Manual Instrumentation to collect traces in the GitHub repository to understand the steps.

Explore trace analytics

OpenSearch Service version 1.3 has a new module to support observability.

  1. Choose the menu icon and look for the Observability section under OpenSearch Plugins.
  2. Choose Trace analytics to examine some of the traces generated by the backend service. If you fail to see sufficient data, increase the time range. Alternatively, choose all the buttons on the sample app webpage for each application service to generate sufficient trace data to debug. You can choose each option multiple times. The following screenshot shows a summarized view of the traces captured.

    The dashboard view groups traces together by trace group name and provides information about average latency, error rate, and trends associated with a particular operation. Latency variance indicates if the latency of a request falls below the 95 percentile or above. If there are multiple trace groups, you can reduce the view by adding filters on various parameters.
  3. Add a filter on the trace group client_checkout.

    The following screenshot shows our filtered results.

    The dashboard also features a map of all the connected services. The Service map helps provide a high-level view on what’s going on in the services based on the color-coding grouped by Latency, Error rate, and Throughput. This helps you identify problems by service.
  4. Choose Error rate to explore the error rate of the connected services.Based on the color-coding in the following diagram, it’s evident that the payment service is throwing errors, whereas other services are working fine without any errors.
  5. Switch to the Latency view, which shows the relative latency in milliseconds with different colors.
    This is useful for troubleshooting bottlenecks in microservices.

    The Trace analytics dashboard also shows distribution of traces over time and trace error rate over time.
  6. To discover the list of traces, under Trace analytics in the navigation pane, choose Traces.
  7. To find the list of services, count of traces per service, and other service-level statistics, choose Services in the navigation pane.

Search traces

Now we want to drill down and learn more about how to troubleshoot errors.

  1. Go back to the Trace analytics dashboard.
  2. Choose Error Rate Service Map and choose the payment service on the graph.The payment service is in dark red. This also sets the payment service filter on the dashboard, and you can see the trace group in the upper pane.
  3. Choose the Traces link of the client_checkout trace group.

    You’re redirected to the Traces page. The list of traces for the client_checkout trace group can be found here.
  4. To view details of the traces, choose Trace IDs.You can see a pie chart showing how much time the trace has spent in each service. The trace is composed of multiple spans, which is defined as a timed operation that represents a piece of workflow in the distributed system. On the right, you can also see time spent in each span, and which have an error.
  5. Copy the trace ID in the client-checkout group.

Log and trace correlation

Although the log and trace data provides valuable information individually, the actual advantage is when we can relate trace data to log data to capture more details about what went wrong. There are three ways we can correlate traces to logs:

  • Runtime – Logs, traces, and metrics can record the moment of time or the range of time the run took place.
  • Run context – This is also known as the request context. It’s standard practice to record the run context (trace and span IDs as well as user-defined context) in the spans. OpenTelemetry extends this practice to logs where possible by including the TraceID and SpanID in the log records. This allows us to directly correlate logs and traces that correspond to the same run context. It also allows us to correlate logs from different components of a distributed system that participated in the particular request.
  • Origin of the telemetry – This is also known as the resource context. OpenTelemetry traces and metrics contain information about the resource they come from. We extend this practice to logs by including the resource in the log records.

These three correlation methods can be the foundation of powerful navigational, filtering, querying, and analytical capabilities. OpenTelemetry aims to record and collect logs in a manner that enables such correlations.

  1. Use the copied traceId from the previous section and search for corresponding logs on the Event analytics page.
    We use the following PPL query:

    source = sample_app_logs | where traceId = “<<trace_id>>”

    Make sure to increase the time range to at least the last hour.

  2. Choose Update to find the corresponding log data for the trace ID.
  3. Choose the expand icon to find more details.This shows you the details of the log including the traceId. This log shows that the payment checkout operation failed. This correlation allowed us to find key information in the log that allows us to go to the application and debug the code.
  4. Choose the Traces tab to see the corresponding trace data linked with the log data.
  5. Choose View surrounding events to discover other events happening at the same time.

This information can be valuable when you want to understand what’s going on in the whole application, particularly how other services are impacted during that time.

Cleanup

This section provides the necessary information for deleting various resources created as part of this post.

It is recommended to perform the below steps after going through the next post of the series.

  1. Execute the following command on the Cloud9 terminal to remove Elastic Kubernetes Service Cluster and its resources.
    eksctl delete cluster --name=observability-cluster

  2. Execute the script to delete the Amazon Elastic Container Registry repositories.
    cd observability-with-amazon-opensearch-blog/scripts
    bash 03-delete-ecr-repo.sh

  3. Delete the CloudFormation stacks in sequence - eksDeploy, AOS-Observability.

Summary

In this post, we deployed an Observability (o11y) Shop microservice application with various services and captured logs and traces from the application. We used FluentBit to capture logs, AWS Distro for Open Telemetry to capture traces, and Data Prepper to collect these logs and traces and send it to OpenSearch Service. We showed how to use the Trace analytics page to look into the captured traces, details about those traces, and service maps to find potential issues. To correlate log and trace data, we demonstrated how to use the Event analytics page to write a simple PPL query to find corresponding log data. The implementation code can be found in the GitHub repository for reference.

The next post in our series covers the use of PPL to create an operational panel to monitor our microservices along with an incident report using notebooks.


About the Author

Subham Rakshit is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

Marvin Gersho is a Senior Solutions Architect at AWS based in New York City. He works with a wide range of startup customers. He previously worked for many years in engineering leadership and hands-on application development, and now focuses on helping customers architect secure and scalable workloads on AWS with a minimum of operational overhead. In his free time, Marvin enjoys cycling and strategy board games.

Rafael Gumiero is a Senior Analytics Specialist Solutions Architect at AWS. An open-source and distributed systems enthusiast, he provides guidance to customers who develop their solutions with AWS Analytics services, helping them optimize the value of their solutions.

How to Automatically Prevent Email Throttling when Reaching Concurrency Limit

Post Syndicated from Mark Richman original https://aws.amazon.com/blogs/messaging-and-targeting/prevent-email-throttling-concurrency-limit/

Introduction

Many users of Amazon Simple Email Service (Amazon SES) send large email campaigns that target tens of thousands of recipients. Regulating the flow of Amazon SES requests can prevent throttling due to exceeding the AWS service limit on the account.

Amazon SES service quotas include a soft limit on the number of emails sent per second (also known as the “sending rate”). This quota is intended to protect users from accidentally sending unintended volumes of email, or from spending more money than intended. Most Amazon SES customers have this quota increased, but very large campaigns may still exceed that limit. As a result, Amazon SES will throttle email requests. When this happens, your messages will fail to reach their destination.

This blog provides users of Amazon SES a mechanism for regulating the flow of messages that are sent to Amazon SES. Cloud Architects, Engineers, and DevOps Engineers designing new, or improving an existing Amazon SES solution would benefit from reading this post.

Overview

A common solution for regulating the flow of API requests to Amazon SES is achieved using Amazon Simple Queue Service (Amazon SQS). Amazon SQS can send, store, and receive messages at virtually any volume and can serve as part of a solution to buffer and throttle the rate of API calls. It achieves this without the need for other services to be available to process the messages. In this solution, Amazon SQS prevents messages from being lost while waiting for them to be sent as emails.

Fig 1 — High level architecture diagram

But this common solution introduces a new challenge. The mechanism used by the Amazon SQS event source mapping for AWS Lambda invokes a function as soon as messages are visible. Our challenge is to regulate the flow of messages, rather than invoke Amazon SES as messages arrive to the queue.

Fig 2 — Leaky bucket

Developers typically limit the flow of messages in a distributed system by implementing the “leaky bucket” algorithm. This algorithm is an analogy to a bucket which has a hole in the bottom from which water leaks out at a constant rate. Water can be added to the bucket intermittently. If too much water is added at once or at too high a rate, the bucket overflows.

In this solution, we prevent this overflow by using throttling. Throttling can be handled in two ways: either before messages reach Amazon SQS, or after messages are removed from the queue (“dequeued”). Both of these methods pose challenges in handling the throttled messages and reprocessing them. These challenges introduce complexity and lead to the excessive use of resources that may cause a snowball effect and make the throttling worse.

Developers often use the following techniques to help improve the successful processing of feeds and submissions:

  • Submit requests at times other than on the hour or on the half hour. For example, submit requests at 11 minutes after the hour or at 41 minutes after the hour. This can have the effect of limiting competition for system resources with other periodic services.
  • Take advantage of times during the day when traffic is likely to be low, such as early evening or early morning hours.

However, these techniques assume that you have control over the rate of requests, which is usually not the case.

Amazon SQS, acting as a highly scalable buffer, allows you to disregard the incoming message rate and store messages at virtually any volume. Therefore, there is no need to throttle messages before adding them to the queue. As long as you eventually process messages faster than you receive new ones, you will be fine with the inflow that will get processed later on.

Regulating flow of messages from Amazon SQS

The proposed solution in this post regulates the dequeue of messages from one or more SQS queues. This approach can help prevent you from exceeding the per-second quota of Amazon SES, thereby preventing Amazon SES from throttling your API calls.

Available configuration controls

When it comes to regulating outflow from Amazon SQS you have a few options. MaxNumberOfMessages controls the maximum number of messages you can dequeue in a single read request. WaitTimeSeconds defines whether Amazon SQS uses short polling (0 seconds wait) or long polling (more than 0 seconds) while waiting to read messages from a queue. Though these capabilities are helpful in many use cases, they don’t provide full control over outflow rates.

Amazon SQS Event source mapping for Lambda is a built-in mechanism that uses a poller within the Lambda service. The poller polls for visible messages in the queue. Once messages are read, they immediately invoke the configured Lambda function. In order to prevent downstream throttling, this solution implements a custom poller to regulate the rate of messages polled instead of the Amazon SQS Event source mechanism.

Custom poller Lambda

Let’s look at the process of implementing a custom poller Lambda function. Your function should actively regulate the outflow rate without throttling or losing any messages.

First, you have to consider how to invoke the poller Lambda function once every second. Using Amazon EventBridge rules you can schedule Lambda invocations at a rate of once per minute. You also have to consider how to complete processing of Amazon SES invocations as soon as possible. And finally, you have to consider how to send requests to Amazon SES at a rate as close as possible to your per-second quota, without exceeding it.

You can use long polling to meet all of these requirements. Using long polling (by setting the WaitTimeSeconds value to a number greater than zero) means the request queries all of the Amazon SQS servers, or waits until the maximum number of messages you can handle per second (the MaxNumberOfMessages value) are read. By setting the MaxNumberOfMessages equal to your Amazon SES request per-second quota, you prevent your requests from exceeding that limit.

By splitting the looping logic from the poll logic (by using two Lambda functions) the code loops every second (60 times per minute) and asynchronously runs the polling logic.

Fig 3 — Custom poller diagram

You can use the following Python code to create the scheduler loop function:

import os
from time import sleep, time_ns

import boto3

SENDER_FUNCTION_NAME = os.getenv("SENDER_FUNCTION_NAME")
lambda_client = boto3.client("lambda")

def lambda_handler(event, context):
    print(event)

    for _ in range(60):
        prev_ns = time_ns()

        response = lambda_client.invoke_async( 
            FunctionName=SENDER_FUNCTION_NAME, InvokeArgs="{}" 
        ) 
        print(response)

        delta_ns = time_ns() - prev_ns

        if delta_ns < 1_000_000_000: 
            secs = (1_000_000_000.0 - delta_ns) / 1_000_000_000 
            sleep(secs)

This Python code creates a poller function:

import json 
import os

import boto3

UNREGULATED_QUEUE_URL = os.getenv("UNREGULATED_QUEUE_URL") 
MAX_NUMBER_OF_MESSAGES = 3 
WAIT_TIME_SECONDS = 1 
CHARSET = "UTF-8"

ses_client = boto3.client("ses") 
sqs_client = boto3.client("sqs")

def lambda_handler(event, context): 
    response = sqs_client.receive_message( 
        QueueUrl=UNREGULATED_QUEUE_URL, 
        MaxNumberOfMessages=MAX_NUMBER_OF_MESSAGES, 
        WaitTimeSeconds=WAIT_TIME_SECONDS, 
    )

    try: 
        messages = response["Messages"] 
    except KeyError: 
        print("No messages in queue") 
        return

    for message in messages: 
        message_body = json.loads(message["Body"]) 
        to_address = message_body["to_address"] 
        from_address = message_body["from_address"] 
        subject = message_body["subject"] 
        body = message_body["body"]

        print(f"Sending email to {to_address}")

        ses_client.send_email( 
            Destination={ 
                "ToAddresses": [ 
                    to_address, 
                ], 
            }, 
            Message={ 
                "Body": { 
                    "Text": { 
                        "Charset": CHARSET, 
                        "Data": body, 
                    } 
                }, 
                "Subject": { 
                    "Charset": CHARSET, 
                    "Data": subject, 
                }, 
            }, 
            Source=from_address, 
        )

        sqs_client.delete_message( 
            QueueUrl=UNREGULATED_QUEUE_URL, ReceiptHandle=message["ReceiptHandle"] 
        )

Regulating flow of prioritized messages from Amazon SQS

In the use case above, you may be serving a very large marketing campaign (“campaign1”) that takes hours to process. At the same time, you may want to process another, much smaller campaign (“campaign2″), which won’t be able to run until campaign1 is complete.

Obvious solution is to prioritize the campaigns by processing both campaigns in parallel. For example, allocate 90% of the Amazon SES per-second capacity limit to process the larger campaign1, while allowing the smaller campaign2 to take 10% of the available capacity under the limit. Amazon SQS does not provide message priority functionalities out-of-the-box. Instead, create two separate queues and poll each queue according to your desired frequency.

Fig 4 — Prioritize campaigns by queue diagram

This solution works fine if you have consistent flow of incoming messages to both queues. Unfortunately, once you finish processing campaign2 you will keep processing campaign1, using only 90% of the limit capacity per second.

Handling unbalanced flow

For handling unbalanced flow of messages merge both of your poller Lambdas. Implement one Lambda that polls both queues for MaxNumberOfMessages (that equals 100% of the limits of both). In this implementation send from your poller Lambda 90% of campaign1 messages and 10% of campaign2 messages. When campaign2 no longer has messages to process, keep processing 100% of the capacity from campaign1’s queue.

Do not delete unsent messages from the queues. These messages will become visible after their queue’s visibility timeout is reached.

To further improve on the previous implementations, introduce a third FIFO Queue to aggregate all messages from both queues and regulate dequeuing from that third FIFO queue. This will allow you to use all available capacity under your SES limit, while interweaving messages from both campaigns at a 1:10 ratio.

Fig 5 — Adding FIFO merge queue diagram

Processing 100% of the available capacity limit of the large campaign1 and 10% of the capacity limit of the small campaign2 allows you to make sure campign2 messages will not wait until campaign1 messages were all processed. Once campain2 messages are all processed, campign1 messages will continue to be processed using 100% of the capacity limit.

You can find here instructions for Configuring Amazon SQS queues.

Conclusion

In this blog post, we have shown you how to regulate the dequeue of Amazon SQS queue messages. This will prevent you from exceeding your Amazon SES per second limit. This will also remove the need to deal with throttled requests. We explained how to combine Amazon SQS, AWS Lambda, Amazon EventBridge to create a custom serverless regulating queue poller. Finally, we described how to regulate the flow of Amazon SES requests when using multiple priority queues. These technics can reduce implementation time for reprocessing throttled requests, optimize utilization of SES request limit, and reduce costs.

About the Authors

This blog post was written by Guy Loewy and Mark Richman, AWS Senior Solutions Architects for SMB.

Building highly resilient applications with on-premises interdependencies using AWS Local Zones

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/building-highly-resilient-applications-with-on-premises-interdependencies-using-aws-local-zones/

This blog post is written by Rachel Rui Liu, Senior Solutions Architect.

AWS Local Zones are a type of infrastructure deployment that places compute, storage, database, and other select AWS services close to large population and industry centers.

Following the successful launch of the AWS Local Zones in 16 US cities since 2019, in Feb 2022, AWS announced plans to launch new AWS Local Zones in 32 metropolitan areas in 26 countries worldwide.

With Local Zones, we’ve seen use cases in two common categories.

The first category of use cases is for workloads that require extremely low latency between end-user devices and workload servers. For example, let’s consider media content creation and real-time multiplayer gaming. For these use cases, deploying the workload to a Local Zone can help achieve down to single-digit milliseconds latency between end-user devices and the AWS infrastructure, which is ideal for a good end-user experience.

This post will focus on addressing the second category of use cases, which is commonly seen in an enterprise hybrid architecture, where customers must achieve low latency between AWS infrastructure and existing on-premises data centers.  Compared to the first category of use cases, these use cases can tolerate slightly higher latency between the end-user devices and the AWS infrastructure. However, these workloads have dependencies to these on-premises systems, so the lowest possible latency between AWS infrastructure and on-premises data centers is required for better application performance. Here are a few examples of these systems:

  • Financial services sector mainframe workloads hosted on premises serving regional customers.
  • Enterprise Active Directory hosted on premise serving cloud and on-premises workloads.
  • Enterprise applications hosted on premises processing a high volume of locally generated data.

For workloads deployed in AWS, the time taken for each interaction with components still hosted in the on-premises data center is increased by the latency. In turn, this delays responses received by the end-user. The total latency accumulates and results in suboptimal user experiences.

By deploying modernized workloads in Local Zones, you can reduce latency while continuing to access systems hosted in on-premises data centers, thereby reducing the total latency for the end-user. At the same time, you can enjoy the benefits of agility, elasticity, and security offered by AWS, and can apply the same automation, compliance, and security best practices that you’ve been familiar with in the AWS Regions.

Enterprise workload resiliency with Local Zones

While designing hybrid architectures with Local Zones, resiliency is an important consideration. You want to route traffic to the nearest Local Zone for low latency. However, when disasters happen, it’s critical to fail over to the parent Region automatically.

Let’s look at the details of hybrid architecture design based on real world deployments from different angles to understand how the architecture achieves all of the design goals.

Hybrid architecture with resilient network connectivity

The following diagram shows a high-level overview of a resilient enterprise hybrid architecture with Local Zones, where you have redundant connections between the AWS Region, the Local Zone, and the corporate data center.

resillient network connectivity

Here are a few key points with this network connectivity design:

  1. Use AWS Direct Connect or Site-to-Site VPN to connect the corporate data center and AWS Region.
  2. Use Direct Connect or self-hosted VPN to connect the corporate data center and the Local Zone. This connection will provide dedicated low-latency connectivity between the Local Zone and corporate data center.
  3. Transit Gateway is a regional service. When attaching the VPC to AWS Transit Gateway, you can only add subnets provisioned in the Region. Instances on subnets in the Local Zone can still use Transit Gateway to reach resources in the Region.
  4. For subnets provisioned in the Region, the VPC route table should be configured to route the traffic to the corporate data center via Transit Gateway.
  5. For subnets provisioned in Local Zone, the VPC route table should be configured to route the traffic to the corporate data center via the self-hosted VPN instance or Direct Connect.

Hybrid architecture with resilient workload deployment

The next examples show a public and a private facing workload.

To simplify the diagram and focus on application layer architecture, the following diagrams assume that you are using Direct Connect to connect between AWS and the on-premises data center.

Example 1: Resilient public facing workload

With a public facing workload, end-user traffic will be routed to the Local Zone. If the Local Zone is unavailable, then the traffic will be routed to the Region automatically using an Amazon Route 53 failover policy.

public facing workload resilliency
Here are the key design considerations for this architecture:

  1. Deploy the workload in the Local Zone and put the compute layer in an AWS AutoScaling Group, so that the application can scale up and down depending on volume of requests.
  2. Deploy the workload in both the Local Zone and an AWS Region, and put the compute layer into an autoscaling group. The regional deployment will act as pilot light or warm standby with minimal footprint. But it can scale out when the Local Zone is unavailable.
  3. Two Application Load Balancers (ALBs) are required: one in the Region and one in the Local Zone. Each ALB will dispatch the traffic to each workload cluster inside the autoscaling group local to it.
  4. An internet gateway is required for public facing workloads. When using a Local Zone, there’s no extra configuration needed: define a single internet gateway and attach it to the VPC.

If you want to specify an Elastic IP address to be the workload’s public endpoint, the Local Zone will have a different address pool than the Region. Noting that BYOIP is unsupported for Local Zones.

  1. Create a Route 53 DNS record with “Failover” as the routing policy.
  • For the primary record, point it to the alias of the ALB in the Local Zone. This will set Local Zone as the preferred destination for the application traffic which minimizes latency for end-users.
  • For the secondary record, point it to the alias of the ALB in the AWS Region.
  • Enable health check for the primary record. If health check against the primary record fails, which indicates that the workload deployed in the Local Zone has failed to respond, then Route 53 will automatically point to the secondary record, which is the workload deployed in the AWS Region.

Example 2: Resilient private workload

For a private workload that’s only accessible by internal users, a few extra considerations must be made to keep the traffic inside of the trusted private network.

private workload resilliency

The architecture for resilient private facing workload has the same steps as public facing workload, but with some key differences. These include:

  1. Instead of using a public hosted zone, create private hosted zones in Route 53 to respond to DNS queries for the workload.
  2. Create the primary and secondary records in Route 53 just like the public workload but referencing the private ALBs.
  3. To allow end-users onto the corporate network (within offices or connected via VPN) to resolve the workload, use the Route 53 Resolver with an inbound endpoint. This allows end-users located on-premises to resolve the records in the private hosted zone. Route 53 Resolver is designed to be integrated with an on-premises DNS server.
  4. No internet gateway is required for hosting the private workload. You might need an internet gateway in the Local Zone for other purposes: for example, to host a self-managed VPN solution to connect the Local Zone with the corporate data center.

Hosting multiple workloads

Customers who host multiple workloads in a single VPC generally must consider how to segregate those workloads. As with workloads in the AWS Region, segregation can be implemented at a subnet or VPC level.

If you want to segregate workloads at the subnet level, you can extend your existing VPC architecture by provisioning extra sets of subnets to the Local Zone.

segregate workloads at subnet level

Although not shown in the diagram, for those of you using a self-hosted VPN to connect the Local Zone with an on-premises data center, the VPN solution can be deployed in a centralized subnet.

You can continue to use security groups, network access control lists (NACLs) , and VPC route tables – just as you would in the Region to segregate the workloads.

If you want to segregate workloads at the VPC level, like many of our customers do, within the Region, inter-VPC routing is generally handled by Transit Gateway. However, in this case, it may be undesirable to send traffic to the Region to reach a subnet in another VPC that is also extended to the Local Zone.

segregate workloads at VPC level

Key considerations for this design are as follows:

  1. Direct Connect is deployed to connect the Local Zone with the corporate data center. Therefore, each VPC will have a dedicated Virtual Private Gateway provisioned to allow association with the Direct Connect Gateway.
  2. To enable inter-VPC traffic within the Local Zone, peer the two VPCs together.
  3. Create a VPC route table in VPC A. Add a route for Subnet Y where the destination is the peering link. Assign this route table to Subnet X.
  4. Create a VPC route table in VPC B. Add a route for Subnet X where the destination is the peering link. Assign this route table to Subnet Y.
  5. If necessary, add routes for on-premises networks and the transit gateway to both route tables.

This design allows traffic between subnets X and Y to stay within the Local Zone, thereby avoiding any latency from the Local Zone to the AWS Region while still permitting full connectivity to all other networks.

Conclusion

In this post, we summarized the use cases for enterprise hybrid architecture with Local Zones, and showed you:

  • Reference architectures to host workloads in Local Zones with low-latency connectivity to corporate data centers and resiliency to enable fail over to the AWS Region automatically.
  • Different design considerations for public and private facing workloads utilizing this hybrid architecture.
  • Segregation and connectivity considerations when extending this hybrid architecture to host multiple workloads.

Hopefully you will be able to follow along with these reference architectures to build and run highly resilient applications with local system interdependencies using Local Zones.

Adding approval notifications to EC2 Image Builder before sharing AMIs

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/adding-approval-notifications-to-ec2-image-builder-before-sharing-amis-2/

­­­­­This blog post is written by, Glenn Chia Jin Wee, Associate Cloud Architect, and Randall Han, Professional Services.

You may be required to manually validate the Amazon Machine Image (AMI) built from an Amazon Elastic Compute Cloud (Amazon EC2) Image Builder pipeline before sharing this AMI to other AWS accounts or to an AWS organization. Currently, Image Builder provides an end-to-end pipeline that automatically shares AMIs after they’ve been built.

In this post, we will walk through the steps to enable approval notifications before AMIs are shared with other AWS accounts. Image Builder supports automated image testing using test components. The recommended best practice is to automate test steps, however situations can arise where test steps become either challenging to automate or internal compliance policies mandate manual checks be conducted prior to distributing images. In such situations, having a manual approval step is useful if you would like to verify the AMI configuration before it is shared to other AWS accounts or an AWS Organization. A manual approval step reduces the potential for sharing an incorrectly configured AMI with other teams which can lead to downstream issues. This solution sends an email with a link to approve or reject the AMI. Users approve the AMI after they’ve verified that it is built according to specifications. Upon approving the AMI, the solution automatically shares it with the specified AWS accounts.

OverviewArchitecture Diagram

  1. In this solution, an Image Builder Pipeline is run that builds a Golden AMI in Account A. After the AMI is built, Image Builder publishes data about the AMI to an Amazon Simple Notification Service (Amazon SNS)
  2. The SNS Topic passes the data to an AWS Lambda function that subscribes to it.
  3. The Lambda function that subscribes to this topic retrieves the data, formats it, and then starts an SSM Automation, passing it the AMI Name and ID.
  4. The first step of the SSM Automation is a manual approval step. The SSM Automation first publishes to an SNS Topic that has an email subscription with the Approver’s email. The approver will receive the email with a URL that they can click to approve the step.
  5. The approval step defines a specific AWS Identity and Access Management (IAM) Role as an approver. This role has the minimum required permissions to approve the manual approval step. After performing manual tests on the Golden AMI, the Approver principal will assume this role.
  6. After assuming this role, the approver will click on the approval link that was sent via email. After approving the step, an AWS Lambda Function is triggered.
  7. This Lambda Function shares the Golden AMI with Account B and sends an email notifying the Target Account Recipients that the AMI has been shared.

Prerequisites

For this walkthrough, you will need the following:

  • Two AWS accounts – one to host the solution resources, and the second which receives the shared Golden AMI.
    • In the account that hosts the solution, prepare an AWS Identity and Access Management (IAM) principal with the sts:AssumeRole permission. This principal must assume the IAM Role that is listed as an approver in the Systems Manager approval step. The ARN of this IAM principal is used in the AWS CloudFormation Approver parameter, This ARN is added to the trust policy of approval IAM Role.
    • In addition, in the account hosting the solution, ensure that the IAM principal deploying the CloudFormation template has the required permissions to create the resources in the stack.
  • A new Amazon Virtual Private Cloud (Amazon VPC) will be created from the stack. Make sure that you have fewer than five VPCs in the selected Region.

Walkthrough

In this section, we will guide you through the steps required to deploy the Image Builder solution. The solution is deployed with CloudFormation.

In this scenario, we deploy the solution within the approver’s account. The approval email will be sent to a predefined email address for manual approval, before the newly created AMI is shared to target accounts.

The approver first assumes the approval IAM Role and then selects the approval link. This leads to the Systems Manager approval page. Upon approval, an email notification will be sent to the predefined target account email address, notifying the relevant stakeholders that the AMI has been successfully shared.

The high-level steps we will follow are:

  1. In Account A, deploy the provided AWS CloudFormation template. This includes an example Image Builder Pipeline, Amazon SNS topics, Lambda functions, and an SSM Automation Document.
  2. Approve the SNS subscription from your supplied email address.
  3. Run the pipeline from the Amazon EC2 Image Builder Console.
  4. [Optional] To conduct manual tests, launch an Amazon EC2 instance from the built AMI after the pipeline runs.
  5. An email will be sent to you with options to approve or reject the step. Ensure that you have assumed the IAM Role that is the approver before clicking the approval link that leads to the SSM console approval page.
  6. Upon approving the step, an AWS Lambda function shares the AMI to the Account B and also sends an email to the target account email recipients notifying them that the AMI has been shared.
  7. Log in to Account B and verify that the AMI has been shared.

Step 1: Deploy the AWS CloudFormation template

1. The CloudFormation template, template.yaml that deploys the solution can also found at this GitHub repository. Follow the instructions at the repository to deploy the stack.

Step 2: Verify your email address

  1. After running the deployment, you will receive an email prompting you to confirm the Subscription at the approver email address. Choose Confirm subscription.

SNS Topic Subscription confirmation email

  1. This leads to the following screen, which shows that your subscription is confirmed.

subscription-confirmation

  1. Repeat the previous 2 steps for the target email address.

Step 3: Run the pipeline from the Image Builder console

  1. In the Image Builder console, under Image pipelines, select the checkbox next to the Pipeline created, choose Actions, and select Run pipeline.

run-image-builder-pipeline

Note: The pipeline takes approximately 20 – 30 minutes to complete.

Step 4: [Optional] Launch an Amazon EC2 instance from the built AMI

If you have a requirement to manually validate the AMI before sharing it with other accounts or to the AWS organization an approver will launch an Amazon EC2 instance from the built AMI and conduct manual tests on the EC2 instance to make sure it is functional.

  1. In the Amazon EC2 console, under Images, choose AMIs. Validate that the AMI is created.

ami-in-account-a

  1. Follow AWS docs: Launching an EC2 instances from a custom AMI for steps on how to launch an Amazon EC2 instance from the AMI.

Step 5: Select the approval URL in the email sent

  1. When the pipeline is run successfully, you will receive another email with a URL to approve the AMI.

approval-email

  1. Before clicking on the Approve link, you must assume the IAM Role that is set as an approver for the Systems Manager step.
  2. In the CloudFormation console, choose the stack that was deployed.

cloudformation-stack

4. Choose Outputs and copy the IAM Role name.

ssm-approval-role-output

5. While logged in as the IAM Principal that has permissions to assume the approval IAM Role, follow the instructions at AWS IAM documentation for switching a role using the console to assume the approval role.
In the Switch Role page, in Role paste the name of the IAM Role that you copied in the previous step.

Note: This IAM Role was deployed with minimum permissions. Hence, seeing warning messages in the console is expected after assuming this role.

switch-role

6. Now in the approval email, select the Approve URL. This leads to the Systems Manager console. Choose Submit.

approve-console

7. After approving the manual step, the second step is executed, which shares the AMI to the target account.

automation-step-success

Step 6: Verify that the AMI is shared to Account B

  1. Log in to Account B.
  2. In the Amazon EC2 console, under Images, choose AMIs. Then, in the dropdown, choose Private images. Validate that the AMI is shared.

verify-ami-in-account-b

  1. Verify that a success email notification was sent to the target account email address provided.

target-email

Clean up

This section provides the necessary information for deleting various resources created as part of this post.

  1. Deregister the AMIs that were created and shared.
    1. Log in to Account A and follow the steps at AWS documentation: Deregister your Linux AMI.
  2. Delete the CloudFormation stack. For instructions, refer to Deleting a stack on the AWS CloudFormation console.

Conclusion

In this post, we explained how to enable approval notifications for an Image Builder pipeline before AMIs are shared to other accounts. This solution can be extended to share to more than one AWS account or even to an AWS organization. With this solution, you will be notified when new golden images are created, allowing you to verify the accuracy of their configuration before sharing them to for wider use. This reduces the possibility of sharing AMIs with misconfigurations that the written tests may not have identified.

We invite you to experiment with different AMIs created using Image Builder, and with different Image Builder components. Check out this GitHub repository for various examples that use Image Builder. Also check out this blog on Image builder integrations with EC2 Auto Scaling Instance Refresh. Let us know your questions and findings in the comments, and have fun!

Fine-tuning Operations at Slice using AWS DevOps Guru

Post Syndicated from Adnan Bilwani original https://aws.amazon.com/blogs/devops/fine-tuning-operations-at-slice-using-aws-devops-guru/

This guest post was authored by Sapan Jain, DevOps Engineer at Slice, and edited by Sobhan Archakam and Adnan Bilwani, at AWS.

Slice empowers over 18,000 independent pizzerias with the modern tools that have grown the major restaurant chains. By uniting these small businesses with specialized technology, marketing, data insights, and shared services, Slice enables them to serve their digitally-minded customers and move away from third-party apps. Using Amazon DevOps Guru, Slice is able to fine-tune their operations to better support these customers.

Serial tech entrepreneur Ilir Sela started Slice to modernize and support his family’s New York City pizzerias. Today, the company partners with restaurants in 3,000 cities and all 50 states, forming the nation’s largest pizza network. For more information, visit slicelife.com.

Slice’s challenge

At Slice, we manage a wide variety of systems, services, and platforms, all with varying levels of complexity. Observability, monitoring, and log aggregation are things we excel at, and they’re always critical for our platform engineering team. However, deriving insights from this data still requires some manual investigation, particularly when dealing with operational anomalies and/or misconfigurations.

To gain automated insights into our services and resources, Slice conducted a proof-of-concept utilizing Amazon DevOps Guru to analyze a small selection of AWS resources. Amazon DevOps Guru identified potential issues in our environment, resulting in actionable insights (ultimately leading to remediation). As a result of this analysis, we enabled Amazon DevOps Guru account-wide, thereby leading to numerous insights into our production environment.

Insights with Amazon DevOps Guru

After we configured Amazon DevOps Guru to begin its account-wide analysis, we left the tool alone to begin the process of collecting and analyzing data. We immediately began seeing some actionable insights for various production AWS resources, some of which are highlighted in the following section:

Amazon DynamoDB Point-in-time recovery

Amazon DynamoDB offers a point-in-time recovery (PITR) feature that provides continuous backups of your DynamoDB data for 35 days to help you protect against accidental write or deletes. If enabled, this lets you restore your respective table to a previous state. Amazon DevOps Guru identified several tables in our environment that had PITR disabled, along with a corresponding Recommendation.

The graphic shows proactive insights for the last 1 month. The one insight shown is 'Dynamo Table Point in Time Recovery not enabled' with a status of OnGoing and a severity of low.

The graphic shows proactive insights for the last 1 month. The one insight shown is 'Dynamo Table Point in Time Recovery not enabled' with a status of OnGoing and a severity of low.

Figure 1. The graphic shows proactive insights for the last 1 month. The one insight shown is ‘Dynamo Table Point in Time Recovery not enabled’ with a status of OnGoing and a severity of low.

Elasticache anomalous evictions

Amazon Elasticache for Redis is used by a handful of our services to cache any relevant application data. Amazon DevOps Guru identified that one of our instances was exhibiting anomalous behavior regarding its cache eviction rate. Essentially, due to the memory pressure of the instance, the eviction rate of cache entries began to increase. DevOps Guru recommended revisiting the sizing of this instance and scaling it vertically or horizontally, where appropriate.

The graph shows the metric: count of ElastiCache evictions plotted for the time period Jul 3, 20:35 to Jul 3, 21:35 UTC. A highlighted section shows that the evictions increased to a peak of 2500 between 21:00 and 21:08. Outside of this interval the evictions are below 500.

The graph shows the metric: count of ElastiCache evictions plotted for the time period Jul 3, 20:35 to Jul 3, 21:35 UTC. A highlighted section shows that the evictions increased to a peak of 2500 between 21:00 and 21:08. Outside of this interval the evictions are below 500.

Figure 2. The graph shows the metric: count of ElastiCache evictions plotted for the time period Jul 3, 20:35 to Jul 3, 21:35 UTC. A highlighted section shows that the evictions increased to a peak of 2500 between 21:00 and 21:08. Outside of this interval the evictions are below 500

AWS Lambda anomalous errors

We manage a few AWS Lambda functions that all serve different purposes. During the beginning of normal work day, we began to see increased error rates for a particular function resulting in an exception being thrown. DevOps Guru was able to detect the increase in error rates and flag them as anomalous. Although retries in this case wouldn’t have solved the problem, it did increase our visibility into the issue (which was also corroborated by our APM platform).

The graph shows the metric: count of AWS/Lambda errors plotted between 11:00 and 13:30 on Jul 6. The sections between the times 11:23 and 12:15 and at 12:37 and 13:13 UTC are highlighted to show the anomalies.

Figure 3. The graph shows the metric: count of AWS/Lambda errors plotted between 11:00 and 13:30 on Jul 6. The sections between the times 11:23 and 12:15 and at 12:37 and 13:13 UTC are highlighted to show the anomalies

Figure 3. The graph shows the metric: count of AWS/Lambda errors plotted between 11:00 and 13:30 on Jul 6. The sections between the times 11:23 and 12:15 UTC are highlighted to show the anomalies

Conclusion

Amazon DevOps Guru integrated into our environment quickly, with no more additional configuration or setup aside from a few button clicks to enable the service. After reviewing several of the proactive insights that DevOps Guru provided, we could formulate plans of action regarding remediation. One specific case example of this is where DevOps Guru flagged several of our Lambda functions for not containing enough subnets. After triaging the finding, we discovered that we were lacking multi-AZ redundancy for several of those functions. As a result, we could implement a change that maximized our availability of those resources.

With the continuous analysis that DevOps Guru performs, we continue to gain new insights into the resources that we utilize and deploy in our environment. This lets us improve operationally while simultaneously maintaining production stability.

About the author:

Adnan Bilwani

Adnan Bilwani is a Sr. Specialist Builders Experience at AWS and part of the AI for DevOps portfolio of services providing fully managed ML-based solutions to enhance your DevOps workflows.

Sobhan Archakam

Sobhan Archakam is a Senior Technical Account Manager at Amazon Web Services. He provides advocacy and guidance to Enterprise Customers to plan, build, deploy and operate solutions at scale using best practices.

Sapan Jain

Sapan Jain is a DevOps Engineer at Slice. He provides support in all facets of DevOps, and has an interest in performance, observability, automation, and troubleshooting.

Use IAM Access Analyzer policy generation to grant fine-grained permissions for your AWS CloudFormation service roles

Post Syndicated from Joel Knight original https://aws.amazon.com/blogs/security/use-iam-access-analyzer-policy-generation-to-grant-fine-grained-permissions-for-your-aws-cloudformation-service-roles/

AWS Identity and Access Management (IAM) Access Analyzer provides tools to simplify permissions management by making it simpler for you to set, verify, and refine permissions. One such tool is IAM Access Analyzer policy generation, which creates fine-grained policies based on your AWS CloudTrail access activity—for example, the actions you use with Amazon Elastic Compute Cloud (Amazon EC2), AWS Lambda, and Amazon Simple Storage Service (Amazon S3). AWS has expanded policy generation capabilities to support the identification of actions used from over 140 services. New additions include services such as AWS CloudFormation, Amazon DynamoDB, and Amazon Simple Queue Service (Amazon SQS). When you request a policy, IAM Access Analyzer generates a policy by analyzing your CloudTrail logs to identify actions used from this group of over 140 services. The generated policy makes it efficient to grant only the required permissions for your workloads. For other services, Access Analyzer helps you by identifying the services used and guides you to add the necessary actions.

In this post, we will show how you can use Access Analyzer to generate an IAM permissions policy that restricts CloudFormation permissions to only those actions that are necessary to deploy a given template, in order to follow the principle of least privilege.

Permissions for AWS CloudFormation

AWS CloudFormation lets you create a collection of related AWS and third-party resources and provision them in a consistent and repeatable fashion. A common access management pattern is to grant developers permission to use CloudFormation to provision resources in the production environment and limit their ability to do so directly. This directs developers to make infrastructure changes in production through CloudFormation, using infrastructure-as-code patterns to manage the changes.

CloudFormation can create, update, and delete resources on the developer’s behalf by assuming an IAM role that has sufficient permissions. Cloud administrators often grant this IAM role broad permissions–in excess of what’s necessary to just create, update, and delete the resources from the developer’s template–because it’s not clear what the minimum permissions are for the template. As a result, the developer could use CloudFormation to create or modify resources outside of what’s required for their workload.

The best practice for CloudFormation is to acquire permissions by using the credentials from an IAM role you pass to CloudFormation. When you attach a least-privilege permissions policy to the role, the actions CloudFormation is allowed to perform can be scoped to only those that are necessary to manage the resources in the template. In this way, you can avoid anti-patterns such as assigning the AdministratorAccess or PowerUserAccess policies—both of which grant excessive permissions—to the role.

The following section will describe how to set up your account and grant these permissions.

Prepare your development account

Within your development account, you will configure the same method for deploying infrastructure as you use in production: passing a role to CloudFormation when you launch a stack. First, you will verify that you have the necessary permissions, and then you will create the role and the role’s permissions policy.

Get permissions to use CloudFormation and IAM Access Analyzer

You will need the following minimal permissions in your development account:

  • Permission to use CloudFormation, in particular to create, update, and delete stacks
  • Permission to pass an IAM role to CloudFormation
  • Permission to create IAM roles and policies
  • Permission to use Access Analyzer, specifically the GetGeneratedPolicy, ListPolicyGenerations, and StartPolicyGeneration actions

The following IAM permissions policy can be used to grant your identity these permissions.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "DeveloperPermissions”,
            "Effect": "Allow",
            "Action": [
                "access-analyzer:GetGeneratedPolicy",
                "access-analyzer:ListPolicyGenerations",
                "access-analyzer:StartPolicyGeneration",
                "cloudformation:*",
                "iam:AttachRolePolicy",
                "iam:CreatePolicy",
                "iam:CreatePolicyVersion",
                "iam:CreateRole",
                "iam:DeletePolicyVersion",
                "iam:DeleteRolePolicy",
                "iam:DetachRolePolicy",
                "iam:GetPolicy",
                "iam:GetPolicyVersion",
                "iam:GetRole",
                "iam:GetRolePolicy",
                "iam:ListPolicies",
                "iam:ListPolicyTags",
                "iam:ListPolicyVersions",
                "iam:ListRolePolicies",
                "iam:ListRoleTags",
                "iam:ListRoles",
                "iam:PutRolePolicy",
                "iam:UpdateAssumeRolePolicy"
            ],
            "Resource": "*"
        },
        {
            "Sid": "AllowPassCloudFormationRole”,
            "Effect": "Allow",
            "Action": [
                "iam:PassRole"
            ]
            "Resource": "*",
            "Condition": {
                "StringEquals": {
                    "iam:PassedToService": "cloudformation.amazonaws.com"
                }
            }
        }
    ]
}

Note: If your identity already has these permissions through existing permissions policies, there is no need to apply the preceding policy to your identity.

Create a role for CloudFormation

Creating a service role for CloudFormation in the development account makes it less challenging to generate the least-privilege policy, because it becomes simpler to identify the actions CloudFormation is taking as it creates and deletes resources defined in the template. By identifying the actions CloudFormation has taken, you can create a permissions policy to match.

To create an IAM role in your development account for CloudFormation

  1. Open the IAM console and choose Roles, then choose Create role.
  2. For the trusted entity, choose AWS service. From the list of services, choose CloudFormation.
  3. Choose Next: Permissions.
  4. Select one or more permissions policies that align with the types of resources your stack will create. For example, if your stack creates a Lambda function and an IAM role, choose the AWSLambda_FullAccess and IAMFullAccess policies.

    Note: Because you have not yet created the least-privilege permissions policy, the role is granted broader permissions than required. You will use this role to launch your stack and evaluate the resulting actions that CloudFormation takes, in order to build a lower-privilege policy.

  5. Choose Next: Tags to proceed.
  6. Enter one or more optional tags, and then choose Next: Review.
  7. Enter a name for the role, such as CloudFormationDevExecRole.
  8. Choose Create role.

Create and destroy the stack

To have CloudFormation exercise the actions required by the stack, you will need to create and destroy the stack.

To create and destroy the stack

  1. Navigate to CloudFormation in the console, expand the menu in the left-hand pane, and choose Stacks.
  2. On the Stacks page, choose Create Stack, and then choose With new resources.
  3. Choose Template is ready, choose Upload a template file, and then select the file for your template. Choose Next.
  4. Enter a Stack name, and then choose Next.
  5. For IAM execution role name, select the name of the role you created in the previous section (CloudFormationDevExecRole). Choose Next.
  6. Review the stack configuration. If present, select the check box(es) in the Capabilities section, and then choose Create stack.
  7. Wait for the stack to reach the CREATE_COMPLETE state before continuing.
  8. From the list of stacks, select the stack you just created, choose Delete, and then choose Delete stack.
  9. Wait until the stack reaches the DELETE_COMPLETE state (at which time it will also disappear from the list of active stacks).

Note: It’s recommended that you also modify the CloudFormation template and update the stack to initiate updates to the deployed resources. This will allow Access Analyzer to capture actions that update the stack’s resources, in addition to create and delete actions. You should also review the API documentation for the resources that are being used in your stack and identify any additional actions that may be required.

Now that the development environment is ready, you can create the least-privilege permissions policy for the CloudFormation role.

Use Access Analyzer to generate a fine-grained identity policy

Access Analyzer reviews the access history in AWS CloudTrail to identify the actions an IAM role has used. Because CloudTrail delivers logs within an average of about 15 minutes of an API call, you should wait at least that long after you delete the stack before you attempt to generate the policy, in order to properly capture all of the actions.

Note: CloudTrail must be enabled in your AWS account in order for policy generation to work. To learn how create a CloudTrail trail, see Creating a trail for your AWS account in the AWS CloudTrail User Guide.

To generate a permissions policy by using Access Analyzer

  1. Open the IAM console and choose Roles. In the search box, enter CloudFormationDevExecRole and select the role name in the list.
  2. On the Permissions tab, scroll down and choose Generate policy based on CloudTrail events to expand this section. Choose Generate policy.
  3. Select the time period of the CloudTrail logs you want analyzed.
  4. Select the AWS Region where you created and deleted the stack, and then select the CloudTrail trail name in the drop-down list.
  5. If this is your first time generating a policy, choose Create and use a new service role to have an IAM role automatically created for you. You can view the permissions policy the role will receive by choosing View permission details. Otherwise, choose Use an existing service role and select a role in the drop-down list.

    The policy generation options are shown in Figure 1.

    Figure 1: Policy generation options

    Figure 1: Policy generation options

  6. Choose Generate policy.

You will be redirected back to the page that shows the CloudFormationDevExecRole role. The Status in the Generate policy based on CloudTrail events section will show In progress. Wait for the policy to be generated, at which time the status will change to Success.

Review the generated policy

You must review and save the generated policy before it can be applied to the role.

To review the generated policy

  1. While you are still viewing the CloudFormationDevExecRole role in the IAM console, under Generate policy based on CloudTrail events, choose View generated policy.
  2. The Generated policy page will open. The Actions included in the generated policy section will show a list of services and one or more actions that were found in the CloudTrail log. Review the list for omissions. Refer to the IAM documentation for a list of AWS services for which an action-level policy can be generated. An example list of services and actions for a CloudFormation template that creates a Lambda function is shown in Figure 2.
    Figure 2: Actions included in the generated policy

    Figure 2: Actions included in the generated policy

  3. Use the drop-down menus in the Add actions for services used section to add any necessary additional actions to the policy for the services that were identified by using CloudTrail. This might be needed if an action isn’t recorded in CloudTrail or if action-level information isn’t supported for a service.

    Note: The iam:PassRole action will not show up in CloudTrail and should be added manually if your CloudFormation template assigns an IAM role to a service (for example, when creating a Lambda function). A good rule of thumb is: If you see iam:CreateRole in the actions, you likely need to also allow iam:PassRole. An example of this is shown in Figure 3.

    Figure 3: Adding PassRole as an IAM action

    Figure 3: Adding PassRole as an IAM action

  4. When you’ve finished adding additional actions, choose Next.

Generated policies contain placeholders that need to be filled in with resource names, AWS Region names, and other variable data. The actual values for these placeholders should be determined based on the content of your CloudFormation template and the Region or Regions you plan to deploy the template to.

To replace placeholders with real values

  • In the generated policy, identify each of the Resource properties that use placeholders in the value, such as ${RoleNameWithPath} or ${Region}. Use your knowledge of the resources that your CloudFormation template creates to properly fill these in with real values.
    • ${RoleNameWithPath} is an example of a placeholder that reflects the name of a resource from your CloudFormation template. Replace the placeholder with the actual name of the resource.
    • ${Region} is an example of a placeholder that reflects where the resource is being deployed, which in this case is the AWS Region. Replace this with either the Region name (for example, us-east-1), or a wildcard character (*), depending on whether you want to restrict the policy to a specific Region or to all Regions, respectively.

For example, a statement from the policy generated earlier is shown following.

{
    "Effect": "Allow",
    "Action": [
        "lambda:CreateFunction",
        "lambda:DeleteFunction",
        "lambda:GetFunction",
        "lambda:GetFunctionCodeSigningConfig"
    ],
    "Resource": "arn:aws:lambda:${Region}:${Account}:function:${FunctionName}"
},

After substituting real values for the placeholders in Resource, it looks like the following.

{
    "Effect": "Allow",
    "Action": [
        "lambda:CreateFunction",
        "lambda:DeleteFunction",
        "lambda:GetFunction",
        "lambda:GetFunctionCodeSigningConfig"
    ],
    "Resource": "arn:aws:lambda:*:123456789012:function:MyLambdaFunction"
},

This statement allows the Lambda actions to be performed on a function named MyLambdaFunction in AWS account 123456789012 in any Region (*). Substitute the correct values for Region, Account, and FunctionName in your policy.

The IAM policy editor window will automatically identify security or other issues in the generated policy. Review and remediate the issues identified in the Security, Errors, Warnings, and Suggestions tabs across the bottom of the window.

To review and remediate policy issues

  1. Use the Errors tab at the bottom of the IAM policy editor window (powered by IAM Access Analyzer policy validation) to help identify any placeholders that still need to be replaced. Access Analyzer policy validation reviews the policy and provides findings that include security warnings, errors, general warnings, and suggestions for your policy. To find more information about the different checks, see Access Analyzer policy validation. An example of policy errors caused by placeholders still being present in the policy is shown in Figure 4.
    Figure 4: Errors identified in the generated policy

    Figure 4: Errors identified in the generated policy

  2. Use the Security tab at the bottom of the editor window to review any security warnings, such as passing a wildcard (*) resource with the iam:PassRole permission. Choose the Learn more link beside each warning for information about remediation. An example of a security warning related to PassRole is shown in Figure 5.
    Figure 5: Security warnings identified in the generated policy

    Figure 5: Security warnings identified in the generated policy

Remediate the PassRole With Star In Resource warning by modifying Resource in the iam:PassRole statement to list the Amazon Resource Name (ARN) of any roles that CloudFormation needs to pass to other services. Additionally, add a condition to restrict which service the role can be passed to. For example, to allow passing a role named MyLambdaRole to the Lambda service, the statement would look like the following.

        {
            "Effect": "Allow",
            "Action": [
                "iam:PassRole"
            ],
            "Resource": [
                "arn:aws:iam::123456789012:role/MyLambdaRole"
            ],
            "Condition": {
                "StringEquals": {
                    "iam:PassedToService": [
                        "lambda.amazonaws.com"
                    ]
                }
            }
        }

The generated policy can now be saved as an IAM policy.

To save the generated policy

  1. In the IAM policy editor window, choose Next.
  2. Enter a name for the policy and an optional description.
  3. Review the Summary section with the list of permissions in the policy.
  4. Enter optional tags in the Tags section.
  5. Choose Create and attach policy.

Test this policy by replacing the existing role policy with this newly generated policy. Then create and destroy the stack again so that the necessary permissions are granted. If the stack fails during creation or deletion, follow the steps to generate the policy again and make sure that the correct values are being used for any iam:PassRole statements.

Deploy the CloudFormation role and policy

Now that you have the least-privilege policy created, you can give this policy to the cloud administrator so that they can deploy the policy and CloudFormation service role into production.

To create a CloudFormation template that the cloud administrator can use

  1. Open the IAM console, choose Policies, and then use the search box to search for the policy you created. Select the policy name in the list.
  2. On the Permissions tab, make sure that the {}JSON button is activated. Select the policy document by highlighting from line 1 all the way to the last line in the policy, as shown in Figure 6.
    Figure 6: Highlighting the generated policy

    Figure 6: Highlighting the generated policy

  3. With the policy still highlighted, use your keyboard to copy the policy into the clipboard (Ctrl-C on Linux or Windows, Option-C on macOS).
  4. Paste the permissions policy JSON object into the following CloudFormation template, replacing the <POLICY-JSON-GOES-HERE> marker. Be sure to indent the left-most curly braces of the JSON object so that they are to the right of the PolicyDocument keyword.
    AWSTemplateFormatVersion: '2010-09-09'
    
    Parameters:
      PolicyName:
        Type: String
        Description: The name of the IAM policy that will be created
    
      RoleName:
        Type: String
        Description: The name of the IAM role that will be created
    
    Resources:
      CfnPolicy:
        Type: AWS::IAM::ManagedPolicy
        Properties:
          ManagedPolicyName: !Ref PolicyName
          Path: /
          PolicyDocument: >
            <POLICY-JSON-GOES-HERE>
    
      CfnRole:
        Type: AWS::IAM::Role
        Properties:
          RoleName: !Ref RoleName
          AssumeRolePolicyDocument:
            Version: '2012-10-17'
            Statement:
              - Action:
                - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - cloudformation.amazonaws.com
          ManagedPolicyArns:
            - !Ref CfnPolicy
          Path: /

    For example, after pasting the policy, the CfnPolicy resource in the template will look like the following.

    CfnPolicy:
        Type: AWS::IAM::ManagedPolicy
        Properties:
          ManagedPolicyName: !Ref PolicyName
          Path: /
          PolicyDocument: >
            {
                "Version": "2012-10-17",
                "Statement": [
                    {
                        "Effect": "Allow",
                        "Action": "ec2:DescribeNetworkInterfaces",
                        "Resource": [
                            "*"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "iam:AttachRolePolicy",
                            "iam:CreateRole",
                            "iam:DeleteRole",
                            "iam:DetachRolePolicy",
                            "iam:GetRole"
                        ],
                        "Resource": [
                            "arn:aws:iam::123456789012:role/MyLambdaRole"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "lambda:CreateFunction",
                            "lambda:DeleteFunction",
                            "lambda:GetFunction",
                            "lambda:GetFunctionCodeSigningConfig"
                        ],
                        "Resource": [
                            "arn:aws:lambda:*:123456789012:function:MyLambdaFunction"
                        ]
                    },
                    {
                        "Effect": "Allow",
                        "Action": [
                            "iam:PassRole"
                        ],
                        "Resource": [
                            "arn:aws:iam::123456789012:role/MyLambdaRole"
                        ],
                        "Condition": {
                            "StringEquals": {
                                "iam:PassedToService": [
                                    "lambda.amazonaws.com"
                                ]
                            }
                        }
                    }
                ]
            }

  5. Save the CloudFormation template and share it with the cloud administrator. They can use this template to create an IAM role and permissions policy that CloudFormation can use to deploy resources in the production account.

Note: Verify that in addition to having the necessary permissions to work with CloudFormation, your production identity also has permission to perform the iam:PassRole action with CloudFormation for the role that the preceding template creates.

As you continue to develop your stack, you will need to repeat the steps in the Use Access Analyzer to create a permissions policy and Deploy the CloudFormation role and policy sections of this post in order to make sure that the permissions policy remains up-to-date with the permissions required to deploy your stack.

Considerations

If your CloudFormation template uses custom resources that are backed by AWS Lambda, you should also run Access Analyzer on the IAM role that is created for the Lambda function in order to build an appropriate permissions policy for that role.

To generate a permissions policy for a Lambda service role

  1. Launch the stack in your development AWS account to create the Lamba function’s role.
  2. Make a note of the name of the role that was created.
  3. Destroy the stack in your development AWS account.
  4. Follow the instructions from the Use Access Analyzer to generate a fine-grained identity policy and Review the generated policy sections of this post to create the least-privilege policy for the role, substituting the Lambda function’s role name for CloudFormationDevExecRole.
  5. Build the resulting least-privilege policy into the CloudFormation template as the Lambda function’s permission policy.

Conclusion

IAM Access Analyzer helps generate fine-grained identity policies that you can use to grant CloudFormation the permissions it needs to create, update, and delete resources in your stack. By granting CloudFormation only the necessary permissions, you can incorporate the principle of least privilege, developers can deploy their stacks in production using reduced permissions, and cloud administrators can create guardrails for developers in production settings.

For additional information on applying the principle of least privilege to AWS CloudFormation, see How to implement the principle of least privilege with CloudFormation StackSets.

If you have feedback about this blog post, submit comments in the Comments section below. You can also start a new thread on AWS Identity and Access Management re:Post to get answers from the community.

Want more AWS Security news? Follow us on Twitter.
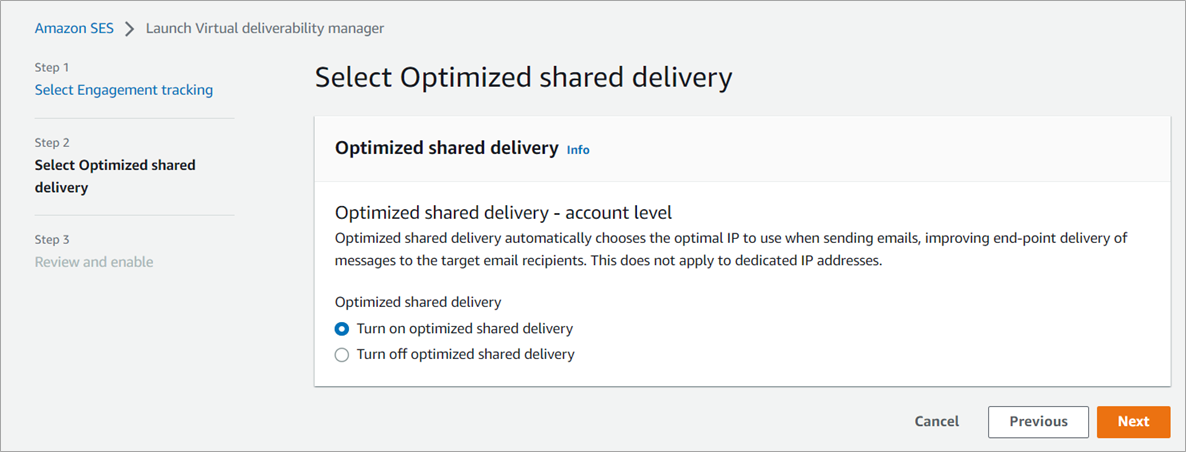
Author

Joel Knight

Joel is a Senior Consultant, Infrastructure Architecture, with AWS and is based in Calgary, Canada. When not wrangling infrastructure-as-code templates, Joel likes to spend time with his family and dabble in home automation.

Mathangi Ramesh

Mathangi Ramesh

Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

Common streaming data enrichment patterns in Amazon Kinesis Data Analytics for Apache Flink

Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/common-streaming-data-enrichment-patterns-in-amazon-kinesis-data-analytics-for-apache-flink/

Stream data processing allows you to act on data in real time. Real-time data analytics can help you have on-time and optimized responses while improving overall customer experience.

Apache Flink is a distributed computation framework that allows for stateful real-time data processing. It provides a single set of APIs for building batch and streaming jobs, making it easy for developers to work with bounded and unbounded data. Apache Flink provides different levels of abstraction to cover a variety of event processing use cases.

Amazon Kinesis Data Analytics is an AWS service that provides a serverless infrastructure for running Apache Flink applications. This makes it easy for developers to build highly available, fault tolerant, and scalable Apache Flink applications without needing to become an expert in building, configuring, and maintaining Apache Flink clusters on AWS.

Data streaming workloads often require data in the stream to be enriched via external sources (such as databases or other data streams). For example, assume you are receiving coordinates data from a GPS device and need to understand how these coordinates map with physical geographic locations; you need to enrich it with geolocation data. You can use several approaches to enrich your real-time data in Kinesis Data Analytics depending on your use case and Apache Flink abstraction level. Each method has different effects on the throughput, network traffic, and CPU (or memory) utilization. In this post, we cover these approaches and discuss their benefits and drawbacks.

Data enrichment patterns

Data enrichment is a process that appends additional context and enhances the collected data. The additional data often is collected from a variety of sources. The format and the frequency of the data updates could range from once in a month to many times in a second. The following table shows a few examples of different sources, formats, and update frequency.

Data Format Update Frequency
IP address ranges by country CSV Once a month
Company organization chart JSON Twice a year
Machine names by ID CSV Once a day
Employee information Table (Relational database) A few times a day
Customer information Table (Non-relational database) A few times an hour
Customer orders Table (Relational database) Many times a second

Based on the use case, your data enrichment application may have different requirements in terms of latency, throughput, or other factors. The remainder of the post dives deeper into different patterns of data enrichment in Kinesis Data Analytics, which are listed in the following table with their key characteristics. You can choose the best pattern based on the trade-off of these characteristics.

Enrichment Pattern Latency Throughput Accuracy if Reference Data Changes Memory Utilization Complexity
Pre-load reference data in Apache Flink Task Manager memory Low High Low High Low
Partitioned pre-loading of reference data in Apache Flink state Low High Low Low Low
Periodic Partitioned pre-loading of reference data in Apache Flink state Low High Medium Low Medium
Per-record asynchronous lookup with unordered map Medium Medium High Low Low
Per-record asynchronous lookup from an external cache system Low or Medium (Depending on Cache storage and implementation) Medium High Low Medium
Enriching streams using the Table API Low High High Low – Medium (depending on the selected join operator) Low

Enrich streaming data by pre-loading the reference data

When the reference data is small in size and static in nature (for example, country data including country code and country name), it’s recommended to enrich your streaming data by pre-loading the reference data, which you can do in several ways.

To see the code implementation for pre-loading reference data in various ways, refer to the GitHub repo. Follow the instructions in the GitHub repository to run the code and understand the data model.

Pre-loading of reference data in Apache Flink Task Manager memory

The simplest and also fastest enrichment method is to load the enrichment data into each of the Apache Flink task managers’ on-heap memory. To implement this method, you create a new class by extending the RichFlatMapFunction abstract class. You define a global static variable in your class definition. The variable could be of any type, the only limitation is that it should extend java.io.Serializable—for example, java.util.HashMap. Within the open() method, you define a logic that loads the static data into your defined variable. The open() method is always called first, during the initialization of each task in Apache Flink’s task managers, which makes sure the whole reference data is loaded before the processing begins. You implement your processing logic by overriding the processElement() method. You implement your processing logic and access the reference data by its key from the defined global variable.

The following architecture diagram shows the full reference data load in each task slot of the task manager.

diagram shows the full reference data load in each task slot of the task manager.

This method has the following benefits:

  • Easy to implement
  • Low latency
  • Can support high throughput

However, it has the following disadvantages:

  • If the reference data is large in size, the Apache Flink task manager may run out of memory.
  • Reference data can become stale over a period of time.
  • Multiple copies of the same reference data are loaded in each task slot of the task manager.
  • Reference data should be small to fit in the memory allocated to a single task slot. In Kinesis Data Analytics, each Kinesis Processing Unit (KPU) has 4 GB of memory, out of which 3 GB can be used for heap memory. If ParallelismPerKPU in Kinesis Data Analytics is set to 1, one task slot runs in each task manager, and the task slot can use the whole 3 GB of heap memory. If ParallelismPerKPU is set to a value greater than 1, the 3 GB of heap memory is distributed across multiple task slots in the task manager. If you’re deploying Apache Flink in Amazon EMR or in a self-managed mode, you can tune taskmanager.memory.task.heap.size to increase the heap memory of a task manager.

Partitioned pre-loading of reference data in Apache Flink State

In this approach, the reference data is loaded and kept in the Apache Flink state store at the start of the Apache Flink application. To optimize the memory utilization, first the main data stream is divided by a specified field via the keyBy() operator across all task slots. Furthermore, only the portion of the reference data that corresponds to each task slot is loaded in the state store.

This is achieved in Apache Flink by creating the class PartitionPreLoadEnrichmentData, extending the RichFlatMapFunction abstract class. Within the open method, you override the ValueStateDescriptor method to create a state handle. In the referenced example, the descriptor is named locationRefData, the state key type is String, and the value type is Location. In this code, we use ValueState compared to MapState because we only hold the location reference data for a particular key. For example, when we query Amazon S3 to get the location reference data, we query for the specific role and get a particular location as a value.

In Apache Flink, ValueState is used to hold a specific value for a key, whereas MapState is used to hold a combination of key-value pairs.

This technique is useful when you have a large static dataset that is difficult to fit in memory as a whole for each partition.

The following architecture diagram shows the load of reference data for the specific key for each partition of the stream.

diagram shows the load of reference data for the specific key for each partition of the stream.

For example, our reference data in the sample GitHub code has roles which are mapped to each building. Because the stream is partitioned by roles, only the specific building information per role is required to be loaded for each partition as the reference data.

This method has the following benefits:

  • Low latency.
  • Can support high throughput.
  • Reference data for specific partition is loaded in the keyed state.
  • In Kinesis Data Analytics, the default state store configured is RocksDB. RocksDB can utilize a significant portion of 1 GB of managed memory and 50 GB of disk space provided by each KPU. This provides enough room for the reference data to grow.

However, it has the following disadvantages:

  • Reference data can become stale over a period of time

Periodic partitioned pre-loading of reference data in Apache Flink State

This approach is a fine-tune of the previous technique, where each partitioned reference data is reloaded on a periodic basis to refresh the reference data. This is useful if your reference data changes occasionally.

The following architecture diagram shows the periodic load of reference data for the specific key for each partition of the stream.

diagram shows the periodic load of reference data for the specific key for each partition of the stream.

In this approach, the class PeriodicPerPartitionLoadEnrichmentData is created, extending the KeyedProcessFunction class. Similar to the previous pattern, in the context of the GitHub example, ValueState is recommended here because each partition only loads a single value for the key. In the same way as mentioned earlier, in the open method, you define the ValueStateDescriptor to handle the value state and define a runtime context to access the state.

Within the processElement method, load the value state and attach the reference data (in the referenced GitHub example, buildingNo to the customer data). Also register a timer service to be invoked when the processing time passes the given time. In the sample code, the timer service is scheduled to be invoked periodically (for example, every 60 seconds). In the onTimer method, update the state by making a call to reload the reference data for the specific role.

This method has the following benefits:

  • Low latency.
  • Can support high throughput.
  • Reference data for specific partitions is loaded in the keyed state.
  • Reference data is refreshed periodically.
  • In Kinesis Data Analytics, the default state store configured is RocksDB. Also, 50 GB of disk space provided by each KPU. This provides enough room for the reference data to grow.

However, it has the following disadvantages:

  • If the reference data changes frequently, the application still has stale data depending on how frequently the state is reloaded
  • The application can face load spikes during reload of reference data

Enrich streaming data using per-record lookup

Although pre-loading of reference data provides low latency and high throughput, it may not be suitable for certain types of workloads, such as the following:

  • Reference data updates with high frequency
  • Apache Flink needs to make an external call to compute the business logic
  • Accuracy of the output is important and the application shouldn’t use stale data

Normally, for these types of use cases, developers trade-off high throughput and low latency for data accuracy. In this section, you learn about a few of common implementations for per-record data enrichment and their benefits and disadvantages.

Per-record asynchronous lookup with unordered map

In a synchronous per-record lookup implementation, the Apache Flink application has to wait until it receives the response after sending every request. This causes the processor to stay idle for a significant period of processing time. Instead, the application can send a request for other elements in the stream while it waits for the response for the first element. This way, the wait time is amortized across multiple requests and therefore it increases the process throughput. Apache Flink provides asynchronous I/O for external data access. While using this pattern, you have to decide between unorderedWait (where it emits the result to the next operator as soon as the response is received, disregarding the order of the element on the stream) and orderedWait (where it waits until all inflight I/O operations complete, then sends the results to the next operator in the same order as original elements were placed on the stream). Usually, when downstream consumers disregard the order of the elements in the stream, unorderedWait provides better throughput and less idle time. Visit Enrich your data stream asynchronously using Kinesis Data Analytics for Apache Flink to learn more about this pattern.

The following architecture diagram shows how an Apache Flink application on Kinesis Data Analytics does asynchronous calls to an external database engine (for example Amazon DynamoDB) for every event in the main stream.

diagram shows how an Apache Flink application on Kinesis Data Analytics does asynchronous calls to an external database engine (for example Amazon DynamoDB) for every event in the main stream.

This method has the following benefits:

  • Still reasonably simple and easy to implement
  • Reads the most up-to-date reference data

However, it has the following disadvantages:

  • It generates a heavy read load for the external system (for example, a database engine or an external API) that hosts the reference data
  • Overall, it might not be suitable for systems that require high throughput with low latency

Per-record asynchronous lookup from an external cache system

A way to enhance the previous pattern is to use a cache system to enhance the read time for every lookup I/O call. You can use Amazon ElastiCache for caching, which accelerates application and database performance, or as a primary data store for use cases that don’t require durability like session stores, gaming leaderboards, streaming, and analytics. ElastiCache is compatible with Redis and Memcached.

For this pattern to work, you must implement a caching pattern for populating data in the cache storage. You can choose between a proactive or reactive approach depending your application objectives and latency requirements. For more information, refer to Caching patterns.

The following architecture diagram shows how an Apache Flink application calls to read the reference data from an external cache storage (for example, Amazon ElastiCache for Redis). Data changes must be replicated from the main database (for example, Amazon Aurora) to the cache storage by implementing one of the caching patterns.

diagram shows how an Apache Flink application calls to read the reference data from an external cache storage (for example, Amazon ElastiCache for Redis). Data changes must be replicated from the main database (for example, Amazon Aurora) to the cache storage by implementing one of the caching patterns.

Implementation for this data enrichment pattern is similar to the per-record asynchronous lookup pattern; the only difference is that the Apache Flink application makes a connection to the cache storage, instead of connecting to the primary database.

This method has the following benefits:

  • Better throughput because caching can accelerate application and database performance
  • Protects the primary data source from the read traffic created by the stream processing application
  • Can provide lower read latency for every lookup call
  • Overall, might not be suitable for medium to high throughput systems that want to improve data freshness

However, it has the following disadvantages:

  • Additional complexity of implementing a cache pattern for populating and syncing the data between the primary database and the cache storage
  • There is a chance for the Apache Flink stream processing application to read stale reference data depending on what caching pattern is implemented
  • Depending on the chosen cache pattern (proactive or reactive), the response time for each enrichment I/O may differ, therefore the overall processing time of the stream could be unpredictable

Alternatively, you can avoid these complexities by using the Apache Flink JDBC connector for Flink SQL APIs. We discuss enrichment stream data via Flink SQL APIs in more detail later in this post.

Enrich stream data via another stream

In this pattern, the data in the main stream is enriched with the reference data in another data stream. This pattern is good for use cases in which the reference data is updated frequently and it’s possible to perform change data capture (CDC) and publish the events to a data streaming service such as Apache Kafka or Amazon Kinesis Data Streams. This pattern is useful in the following use cases, for example:

  • Customer purchase orders are published to a Kinesis data stream, and then join with customer billing information in a DynamoDB stream
  • Data events captured from IoT devices should enrich with reference data in a table in Amazon Relational Database Service (Amazon RDS)
  • Network log events should enrich with the machine name on the source (and the destination) IP addresses

The following architecture diagram shows how an Apache Flink application on Kinesis Data Analytics joins data in the main stream with the CDC data in a DynamoDB stream.

diagram shows how an Apache Flink application on Kinesis Data Analytics joins data in the main stream with the CDC data in a DynamoDB stream.

To enrich streaming data from another stream, we use a common stream to stream join patterns, which we explain in the following sections.

Enrich streams using the Table API

Apache Flink Table APIs provide higher abstraction for working with data events. With Table APIs, you can define your data stream as a table and attach the data schema to it.

In this pattern, you define tables for each data stream and then join those tables to achieve the data enrichment goals. Apache Flink Table APIs support different types of join conditions, like inner join and outer join. However, you want to avoid those if you’re dealing with unbounded streams because those are resource intensive. To limit the resource utilization and run joins effectively, you should use either interval or temporal joins. An interval join requires one equi-join predicate and a join condition that bounds the time on both sides. To better understand how to implement an interval join, refer to Get started with Apache Flink SQL APIs in Kinesis Data Analytics Studio.

Compared to interval joins, temporal table joins don’t work with a time period within which different versions of a record are kept. Records from the main stream are always joined with the corresponding version of the reference data at the time specified by the watermark. Therefore, fewer versions of the reference data remain in the state.

Note that the reference data may or may not have a time element associated with it. If it doesn’t, you may need to add a processing time element for the join with the time-based stream.

In the following example code snippet, the update_time column is added to the currency_rates reference table from the change data capture metadata such as Debezium. Furthermore, it’s used to define a watermark strategy for the table.

CREATE TABLE currency_rates (
    currency STRING,
    conversion_rate DECIMAL(32, 2),
    update_time TIMESTAMP(3) METADATA FROM `values.source.timestamp` VIRTUAL,
        WATERMARK FOR update_time AS update_time,
    PRIMARY KEY(currency) NOT ENFORCED
) WITH (
   'connector' = 'kafka',
   'value.format' = 'debezium-json',
   /* ... */
);

This method has the following benefits:
  • Easy to implement
  • Low latency
  • Can support high throughput when reference data is a data stream

SQL APIs provide higher abstractions over how the data is processed. For more complex logic around how the join operator should process, we recommend you always start with SQL APIs first and use DataStream APIs if you really need to.

Conclusion

In this post, we demonstrated different data enrichment patterns in Kinesis Data Analytics. You can use these patterns and find the one that addresses your needs and quickly develop a stream processing application.

For further reading on Kinesis Data Analytics, visit the official product page.


About the Authors

About the author Ali AlemiAli Alemi is a Streaming Specialist Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems that are reliable, secure, efficient, and cost-effective. He works backward from customers’ use cases and designs data solutions to solve their business problems. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the cloud.

About the author Subham RakshitSubham Rakshit is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

About the author Dr. Sam MokhtariDr. Sam Mokhtari is a Senior Solutions Architect in AWS. His main area of depth is data and analytics, and he has published more than 30 influential articles in this field. He is also a respected data and analytics advisor who led several large-scale implementation projects across different industries, including energy, health, telecom, and transport.

IAM Access Analyzer makes it simpler to author and validate role trust policies

Post Syndicated from Mathangi Ramesh original https://aws.amazon.com/blogs/security/iam-access-analyzer-makes-it-simpler-to-author-and-validate-role-trust-policies/

AWS Identity and Access Management (IAM) Access Analyzer provides many tools to help you set, verify, and refine permissions. One part of IAM Access Analyzer—policy validation—helps you author secure and functional policies that grant the intended permissions. Now, I’m excited to announce that AWS has updated the IAM console experience for role trust policies to make it simpler for you to author and validate the policy that controls who can assume a role. In this post, I’ll describe the new capabilities and show you how to use them as you author a role trust policy in the IAM console.

Overview of changes

A role trust policy is a JSON policy document in which you define the principals that you trust to assume the role. The principals that you can specify in the trust policy include users, roles, accounts, and services. The new IAM console experience provides the following features to help you set the right permissions in the trust policy:

  • An interactive policy editor prompts you to add the right policy elements, such as the principal and the allowed actions, and offers context-specific documentation.
  • As you author the policy, IAM Access Analyzer runs over 100 checks against your policy and highlights issues to fix. This includes new policy checks specific to role trust policies, such as a check to make sure that you’ve formatted your identity provider correctly. These new checks are also available through the IAM Access Analyzer policy validation API.
  • Before saving the policy, you can preview findings for the external access granted by your trust policy. This helps you review external access, such as access granted to a federated identity provider, and confirm that you grant only the intended access when you create the policy. This functionality was previously available through the APIs, but now it’s also available in the IAM console.

In the following sections, I’ll walk you through how to use these new features.

Example scenario

For the walkthrough, consider the following example, which is illustrated in Figure 1. You are a developer for Example Corp., and you are working on a web application. You want to grant the application hosted in one account—the ApplicationHost account—access to data in another account—the BusinessData account. To do this, you can use an IAM role in the BusinessData account to grant temporary access to the application through a role trust policy. You will grant a role in the ApplicationHost account—the PaymentApplication role—to access the BusinessData account through a role—the ApplicationAccess role. In this example, you create the ApplicationAccess role and grant cross-account permissions through the trust policy by using the new IAM console experience that helps you set the right permissions.

Figure 1: Visual explanation of the scenario

Figure 1: Visual explanation of the scenario

Create the role and grant permissions through a role trust policy with the policy editor

In this section, I will show you how to create a role trust policy for the ApplicationAccess role to grant the application access to the data in your account through the policy editor in the IAM console.

To create a role and grant access

  1. In the BusinessData account, open the IAM console, and in the left navigation pane, choose Roles.
  2. Choose Create role, and then select Custom trust policy, as shown in Figure 2.
    Figure 2: Select "Custom trust policy" when creating a role

    Figure 2: Select “Custom trust policy” when creating a role

  3. In the Custom trust policy section, for 1. Add actions for STS, select the actions that you need for your policy. For example, to add the action sts:AssumeRole, choose AssumeRole.
    Figure 3: JSON role trust policy

    Figure 3: JSON role trust policy

  4. For 2. Add a principal, choose Add to add a principal.
  5. In the Add principal box, for Principal type, select IAM roles. This populates the ARN field with the format of the role ARN that you need to add to the policy, as shown in Figure 4.
    Figure 4: Add a principal to your role trust policy

    Figure 4: Add a principal to your role trust policy

  6. Update the role ARN template with the actual account and role information, and then choose Add principal. In our example, the account is ApplicationHost with an AWS account number of 111122223333, and the role is PaymentApplication role. Therefore, the role ARN is arn:aws:iam:: 111122223333: role/PaymentApplication. Figure 5 shows the role trust policy with the action and principal added.
    Figure 5: Sample role trust policy

    Figure 5: Sample role trust policy

  7. (Optional) To add a condition, for 3. Add a condition, choose Add, and then complete the Add condition box according to your needs.

Author secure policies by reviewing policy validation findings

As you author the policy, you can see errors or warnings related to your policy in the policy validation window, which is located below the policy editor in the console. With this launch, policy validation in IAM Access Analyzer includes 13 new checks focused on the trust relationship for the role. The following are a few examples of these checks and how to address them:

  • Role trust policy unsupported wildcard in principal – you can’t use a * in your role trust policy.
  • Invalid federated principal syntax in role trust policy – you need to fix the format of the identity provider.
  • Missing action for condition key – you need to add the right action for a given condition, such as the sts:TagSession when there are session tag conditions.

For a complete list of checks, see Access Analyzer policy check reference.

To review and fix policy validation findings

  1. In the policy validation window, do the following:
    • Choose the Security tab to check if your policy is overly permissive.
    • Choose the Errors tab to review any errors associated with the policy.
    • Choose the Warnings tab to review if aspects of the policy don’t align with AWS best practices.
    • Choose the Suggestions tab to get recommendations on how to improve the quality of your policy.
    Figure 6: Policy validation window in IAM Access Analyzer with a finding for your policy

    Figure 6: Policy validation window in IAM Access Analyzer with a finding for your policy

  2. For each finding, choose Learn more to review the documentation associated with the finding and take steps to fix it. For example, Figure 6 shows the error Mismatched Action For Principal. To fix the error, remove the action sts:AssumeRoleWithWebIdentity.

Preview external access by reviewing cross-account access findings

IAM Access Analyzer also generates findings to help you assess if a policy grants access to external entities. You can review the findings before you create the policy to make sure that the policy grants only intended access. To preview the findings, you create an analyzer and then review the findings.

To preview findings for external access

  1. Below the policy editor, in the Preview external access section, choose Go to Access Analyzer, as shown in Figure 7.

    Note: IAM Access Analyzer is a regional service, and you can create a new analyzer in each AWS Region where you operate. In this situation, IAM Access Analyzer looks for an analyzer in the Region where you landed on the IAM console. If IAM Access Analyzer doesn’t find an analyzer there, it asks you to create an analyzer.

    Figure 7: Preview external access widget without an analyzer

    Figure 7: Preview external access widget without an analyzer

  2. On the Create analyzer page, do the following to create an analyzer:
    • For Name, enter a name for your analyzer.
    • For Zone of trust, select the correct account.
    • Choose Create analyzer.
    Figure 8: Create an analyzer to preview findings

    Figure 8: Create an analyzer to preview findings

  3. After you create the analyzer, navigate back to the role trust policy for your role to review the external access granted by this policy. The following figure shows that external access is granted to PaymentApplication.
    Figure 9: Preview finding

    Figure 9: Preview finding

  4. If the access is intended, you don’t need to take any action. In this example, I want the PaymentApplication role in the ApplicationHost account to assume the role that I’m creating.
  5. If the access is unintended, resolve the finding by updating the role ARN information.
  6. Select Next and grant the required IAM permissions for the role.
  7. Name the role ApplicationAccess, and then choose Save to save the role.

Now the application can use this role to access the BusinessData account.

Conclusion

By using the new IAM console experience for role trust policies, you can confidently author policies that grant the intended access. IAM Access Analyzer helps you in your least-privilege journey by evaluating the policy for potential issues to make it simpler for you to author secure policies. IAM Access Analyzer also helps you preview external access granted through the trust policy to help ensure that the granted access is intended. To learn more about how to preview IAM Access Analyzer cross-account findings, see Preview access in the documentation. To learn more about IAM Access Analyzer policy validation checks, see Access Analyzer policy validation. These features are also available through APIs.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread at AWS IAM re:Post or contact AWS Support.

Mathangi Ramesh

Mathangi Ramesh

Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

Build, Test and Deploy ETL solutions using AWS Glue and AWS CDK based CI/CD pipelines

Post Syndicated from Puneet Babbar original https://aws.amazon.com/blogs/big-data/build-test-and-deploy-etl-solutions-using-aws-glue-and-aws-cdk-based-ci-cd-pipelines/

AWS Glue is a serverless data integration service that makes it easy to discover, prepare, and combine data for analytics, machine learning (ML), and application development. It’s serverless, so there’s no infrastructure to set up or manage.

This post provides a step-by-step guide to build a continuous integration and continuous delivery (CI/CD) pipeline using AWS CodeCommit, AWS CodeBuild, and AWS CodePipeline to define, test, provision, and manage changes of AWS Glue based data pipelines using the AWS Cloud Development Kit (AWS CDK).

The AWS CDK is an open-source software development framework for defining cloud infrastructure as code using familiar programming languages and provisioning it through AWS CloudFormation. It provides you with high-level components called constructs that preconfigure cloud resources with proven defaults, cutting down boilerplate code and allowing for faster development in a safe, repeatable manner.

Solution overview

The solution constructs a CI/CD pipeline with multiple stages. The CI/CD pipeline constructs a data pipeline using COVID-19 Harmonized Data managed by Talend / Stitch. The data pipeline crawls the datasets provided by neherlab from the public Amazon Simple Storage Service (Amazon S3) bucket, exposes the public datasets in the AWS Glue Data Catalog so they’re available for SQL queries using Amazon Athena, performs ETL (extract, transform, and load) transformations to denormalize the datasets to a table, and makes the denormalized table available in the Data Catalog.

The solution is designed as follows:

  • A data engineer deploys the initial solution. The solution creates two stacks:
    • cdk-covid19-glue-stack-pipeline – This stack creates the CI/CD infrastructure as shown in the architectural diagram (labeled Tool Chain).
    • cdk-covid19-glue-stack – The cdk-covid19-glue-stack-pipeline stack deploys the cdk-covid19-glue-stack stack to create the AWS Glue based data pipeline as shown in the diagram (labeled ETL).
  • The data engineer makes changes on cdk-covid19-glue-stack (when a change in the ETL application is required).
  • The data engineer pushes the change to a CodeCommit repository (generated in the cdk-covid19-glue-stack-pipeline stack).
  • The pipeline is automatically triggered by the push, and deploys and updates all the resources in the cdk-covid19-glue-stack stack.

At the time of publishing of this post, the AWS CDK has two versions of the AWS Glue module: @aws-cdk/aws-glue and @aws-cdk/aws-glue-alpha, containing L1 constructs and L2 constructs, respectively. At this time, the @aws-cdk/aws-glue-alpha module is still in an experimental stage. We use the stable @aws-cdk/aws-glue module for the purpose of this post.

The following diagram shows all the components in the solution.

BDB-2467-architecture-diagram

Figure 1 – Architecture diagram

The data pipeline consists of an AWS Glue workflow, triggers, jobs, and crawlers. The AWS Glue job uses an AWS Identity and Access Management (IAM) role with appropriate permissions to read and write data to an S3 bucket. AWS Glue crawlers crawl the data available in the S3 bucket, update the AWS Glue Data Catalog with the metadata, and create tables. You can run SQL queries on these tables using Athena. For ease of identification, we followed the naming convention for triggers to start with t_*, crawlers with c_*, and jobs with j_*. A CI/CD pipeline based on CodeCommit, CodeBuild, and CodePipeline builds, tests and deploys the solution. The complete infrastructure is created using the AWS CDK.

The following table lists the tables created by this solution that you can query using Athena.

Table Name Description Dataset Location Access Location
neherlab_case_counts Total number of cases s3://covid19-harmonized-dataset/covid19tos3/neherlab_case_counts/ Read Public
neherlab_country_codes Country code s3://covid19-harmonized-dataset/covid19tos3/neherlab_country_codes/ Read Public
neherlab_icu_capacity Intensive Care Unit (ICU) capacity s3://covid19-harmonized-dataset/covid19tos3/neherlab_icu_capacity/ Read Public
neherlab_population Population s3://covid19-harmonized-dataset/covid19tos3/neherlab_population/ Read Public
neherla_denormalized Denormalized table that combines all the preceding tables into one table s3://<your-S3-bucket-name>/neherlab_denormalized Read/Write Reader’s AWS account

Anatomy of the AWS CDK application

In this section, we visit key concepts and anatomy of the AWS CDK application, review the important sections of the code, and discuss how the AWS CDK reduces complexity of the solution as compared to AWS CloudFormation.

An AWS CDK app defines one or more stacks. Stacks (equivalent to CloudFormation stacks) contain constructs, each of which defines one or more concrete AWS resources. Each stack in the AWS CDK app is associated with an environment. An environment is the target AWS account ID and Region into which the stack is intended to be deployed.

In the AWS CDK, the top-most object is the AWS CDK app, which contains multiple stacks vs. the top-level stack in AWS CloudFormation. Given this difference, you can define all the stacks required for the application in the AWS CDK app. In AWS Glue based ETL projects, developers need to define multiple data pipelines by subject area or business logic. In AWS CloudFormation, we can achieve this by writing multiple CloudFormation stacks and often deploy them independently. In some cases, developers write nested stacks, which over time becomes very large and complicated to maintain. In the AWS CDK, all stacks are deployed from the AWS CDK app, increasing modularity of the code and allowing developers to identify all the data pipelines associated with an application easily.

Our AWS CDK application consists of four main files:

  • app.py – This is the AWS CDK app and the entry point for the AWS CDK application
  • pipeline.py – The pipeline.py stack, invoked by app.py, creates the CI/CD pipeline
  • etl/infrastructure.py – The etl/infrastructure.py stack, invoked by pipeline.py, creates the AWS Glue based data pipeline
  • default-config.yaml – The configuration file contains the AWS account ID and Region.

The AWS CDK application reads the configuration from the default-config.yaml file, sets the environment information (AWS account ID and Region), and invokes the PipelineCDKStack class in pipeline.py. Let’s break down the preceding line and discuss the benefits of this design.

For every application, we want to deploy in pre-production environments and a production environment. The application in all the environments will have different configurations, such as the size of the deployed resources. In the AWS CDK, every stack has a property called env, which defines the stack’s target environment. This property receives the AWS account ID and Region for the given stack.

Lines 26–34 in app.py show the aforementioned details:

# Initiating the CodePipeline stack
PipelineCDKStack(
app,
"PipelineCDKStack",
config=config,
env=env,
stack_name=config["codepipeline"]["pipelineStackName"]
)

The env=env line sets the target AWS account ID and Region for PipelieCDKStack. This design allows an AWS CDK app to be deployed in multiple environments at once and increases the parity of the application in all environment. For our example, if we want to deploy PipelineCDKStack in multiple environments, such as development, test, and production, we simply call the PipelineCDKStack stack after populating the env variable appropriately with the target AWS account ID and Region. This was more difficult in AWS CloudFormation, where developers usually needed to deploy the stack for each environment individually. The AWS CDK also provides features to pass the stage at the command line. We look into this option and usage in the later section.

Coming back to the AWS CDK application, the PipelineCDKStack class in pipeline.py uses the aws_cdk.pipeline construct library to create continuous delivery of AWS CDK applications. The AWS CDK provides multiple opinionated construct libraries like aws_cdk.pipeline to reduce boilerplate code from an application. The pipeline.py file creates the CodeCommit repository, populates the repository with the sample code, and creates a pipeline with the necessary AWS CDK stages for CodePipeline to run the CdkGlueBlogStack class from the etl/infrastructure.py file.

Line 99 in pipeline.py invokes the CdkGlueBlogStack class.

The CdkGlueBlogStack class in etl/infrastructure.py creates the crawlers, jobs, database, triggers, and workflow to provision the AWS Glue based data pipeline.

Refer to line 539 for creating a crawler using the CfnCrawler construct, line 564 for creating jobs using the CfnJob construct, and line 168 for creating the workflow using the CfnWorkflow construct. We use the CfnTrigger construct to stitch together multiple triggers to create the workflow. The AWS CDK L1 constructs expose all the available AWS CloudFormation resources and entities using methods from popular programing languages. This allows developers to use popular programing languages to provision resources instead of working with JSON or YAML files in AWS CloudFormation.

Refer to etl/infrastructure.py for additional details.

Walkthrough of the CI/CD pipeline

In this section, we walk through the various stages of the CI/CD pipeline. Refer to CDK Pipelines: Continuous delivery for AWS CDK applications for additional information.

  • Source – This stage fetches the source of the AWS CDK app from the CodeCommit repo and triggers the pipeline every time a new commit is made.
  • Build – This stage compiles the code (if necessary), runs the tests, and performs a cdk synth. The output of the step is a cloud assembly, which is used to perform all the actions in the rest of the pipeline. The pytest is run using the amazon/aws-glue-libs:glue_libs_3.0.0_image_01 Docker image. This image comes with all the required libraries to run tests for AWS Glue version 3.0 jobs using a Docker container. Refer to Develop and test AWS Glue version 3.0 jobs locally using a Docker container for additional information.
  • UpdatePipeline – This stage modifies the pipeline if necessary. For example, if the code is updated to add a new deployment stage to the pipeline or add a new asset to your application, the pipeline is automatically updated to reflect the changes.
  • Assets – This stage prepares and publishes all AWS CDK assets of the app to Amazon S3 and all Docker images to Amazon Elastic Container Registry (Amazon ECR). When the AWS CDK deploys an app that references assets (either directly by the app code or through a library), the AWS CDK CLI first prepares and publishes the assets to Amazon S3 using a CodeBuild job. This AWS Glue solution creates four assets.
  • CDKGlueStage – This stage deploys the assets to the AWS account. In this case, the pipeline deploys the AWS CDK template etl/infrastructure.py to create all the AWS Glue artifacts.

Code

The code can be found at AWS Samples on GitHub.

Prerequisites

This post assumes you have the following:

Deploy the solution

To deploy the solution, complete the following steps:

  • Download the source code from the AWS Samples GitHub repository to the client machine:
$ git clone [email protected]:aws-samples/aws-glue-cdk-cicd.git
  • Create the virtual environment:
$ cd aws-glue-cdk-cicd 
$ python3 -m venv .venv

This step creates a Python virtual environment specific to the project on the client machine. We use a virtual environment in order to isolate the Python environment for this project and not install software globally.

  • Activate the virtual environment according to your OS:
    • On MacOS and Linux, use the following code:
$ source .venv/bin/activate
    • On a Windows platform, use the following code:
% .venv\Scripts\activate.bat

After this step, the subsequent steps run within the bounds of the virtual environment on the client machine and interact with the AWS account as needed.

  • Install the required dependencies described in requirements.txt to the virtual environment:
$ pip install -r requirements.txt
  • Bootstrap the AWS CDK app:
cdk bootstrap

This step populates a given environment (AWS account ID and Region) with resources required by the AWS CDK to perform deployments into the environment. Refer to Bootstrapping for additional information. At this step, you can see the CloudFormation stack CDKToolkit on the AWS CloudFormation console.

  • Synthesize the CloudFormation template for the specified stacks:
$ cdk synth # optional if not default (-c stage=default)

You can verify the CloudFormation templates to identify the resources to be deployed in the next step.

  • Deploy the AWS resources (CI/CD pipeline and AWS Glue based data pipeline):
$ cdk deploy # optional if not default (-c stage=default)

At this step, you can see CloudFormation stacks cdk-covid19-glue-stack-pipeline and cdk-covid19-glue-stack on the AWS CloudFormation console. The cdk-covid19-glue-stack-pipeline stack gets deployed first, which in turn deploys cdk-covid19-glue-stack to create the AWS Glue pipeline.

Verify the solution

When all the previous steps are complete, you can check for the created artifacts.

CloudFormation stacks

You can confirm the existence of the stacks on the AWS CloudFormation console. As shown in the following screenshot, the CloudFormation stacks have been created and deployed by cdk bootstrap and cdk deploy.

BDB-2467-cloudformation-stacks

Figure 2 – AWS CloudFormation stacks

CodePipeline pipeline

On the CodePipeline console, check for the cdk-covid19-glue pipeline.

BDB-2467-code-pipeline-summary

Figure 3 – AWS CodePipeline summary view

You can open the pipeline for a detailed view.

BDB-2467-code-pipeline-detailed

Figure 4 – AWS CodePipeline detailed view

AWS Glue workflow

To validate the AWS Glue workflow and its components, complete the following steps:

  • On the AWS Glue console, choose Workflows in the navigation pane.
  • Confirm the presence of the Covid_19 workflow.
BDB-2467-glue-workflow-summary

Figure 5 – AWS Glue Workflow summary view

You can select the workflow for a detailed view.

BDB-2467-glue-workflow-detailed

Figure 6 – AWS Glue Workflow detailed view

  • Choose Triggers in the navigation pane and check for the presence of seven t-* triggers.
BDB-2467-glue-triggers

Figure 7 – AWS Glue Triggers

  • Choose Jobs in the navigation pane and check for the presence of three j_* jobs.
BDB-2467-glue-jobs

Figure 8 – AWS Glue Jobs

The jobs perform the following tasks:

    • etlScripts/j_emit_start_event.py – A Python job that starts the workflow and creates the event
    • etlScripts/j_neherlab_denorm.py – A Spark ETL job to transform the data and create a denormalized view by combining all the base data together in Parquet format
    • etlScripts/j_emit_ended_event.py – A Python job that ends the workflow and creates the specific event
  • Choose Crawlers in the navigation pane and check for the presence of five neherlab-* crawlers.
BDB-2467-glue-crawlers

Figure 9 – AWS Glue Crawlers

Execute the solution

  • The solution creates a scheduled AWS Glue workflow which runs at 10:00 AM UTC on day 1 of every month. A scheduled workflow can also be triggered on-demand. For the purpose of this post, we will execute the workflow on-demand using the following command from the AWS CLI. If the workflow is successfully started, the command returns the run ID. For instructions on how to run and monitor a workflow in Amazon Glue, refer to Running and monitoring a workflow in Amazon Glue.
aws glue start-workflow-run --name Covid_19
  • You can verify the status of a workflow run by execution the following command from the AWS CLI. Please use the run ID returned from the above command. A successfully executed Covid_19 workflow should return a value of 7 for SucceededActions  and 0 for FailedActions.
aws glue get-workflow-run --name Covid_19 --run-id <run_ID>
  • A sample output of the above command is provided below.
{
"Run": {
"Name": "Covid_19",
"WorkflowRunId": "wr_c8855e82ab42b2455b0e00cf3f12c81f957447abd55a573c087e717f54a4e8be",
"WorkflowRunProperties": {},
"StartedOn": "2022-09-20T22:13:40.500000-04:00",
"CompletedOn": "2022-09-20T22:21:39.545000-04:00",
"Status": "COMPLETED",
"Statistics": {
"TotalActions": 7,
"TimeoutActions": 0,
"FailedActions": 0,
"StoppedActions": 0,
"SucceededActions": 7,
"RunningActions": 0
}
}
}
  • (Optional) To verify the status of the workflow run using AWS Glue console, choose Workflows in the navigation pane, select the Covid_19 workflow, click on the History tab, select the latest row and click on View run details. A successfully completed workflow is marked in green check marks. Please refer to the Legend section in the below screenshot for additional statuses.

    BDB-2467-glue-workflow-success

    Figure 10 – AWS Glue Workflow successful run

Check the output

  • When the workflow is complete, navigate to the Athena console to check the successful creation and population of neherlab_denormalized table. You can run SQL queries against all 5 tables to check the data. A sample SQL query is provided below.
SELECT "country", "location", "date", "cases", "deaths", "ecdc-countries",
        "acute_care", "acute_care_per_100K", "critical_care", "critical_care_per_100K" 
FROM "AwsDataCatalog"."covid19db"."neherlab_denormalized"
limit 10;
BDB-2467-athena

Figure 10 – Amazon Athena

Clean up

To clean up the resources created in this post, delete the AWS CloudFormation stacks in the following order:

  • cdk-covid19-glue-stack
  • cdk-covid19-glue-stack-pipeline
  • CDKToolkit

Then delete all associated S3 buckets:

  • cdk-covid19-glue-stack-p-pipelineartifactsbucketa-*
  • cdk-*-assets-<AWS_ACCOUNT_ID>-<AWS_REGION>
  • covid19-glue-config-<AWS_ACCOUNT_ID>-<AWS_REGION>
  • neherlab-denormalized-dataset-<AWS_ACCOUNT_ID>-<AWS_REGION>

Conclusion

In this post, we demonstrated a step-by-step guide to define, test, provision, and manage changes to an AWS Glue based ETL solution using the AWS CDK. We used an AWS Glue example, which has all the components to build a complex ETL solution, and demonstrated how to integrate individual AWS Glue components into a frictionless CI/CD pipeline. We encourage you to use this post and associated code as the starting point to build your own CI/CD pipelines for AWS Glue based ETL solutions.


About the authors

Puneet Babbar is a Data Architect at AWS, specialized in big data and AI/ML. He is passionate about building products, in particular products that help customers get more out of their data. During his spare time, he loves to spend time with his family and engage in outdoor activities including hiking, running, and skating. Connect with him on LinkedIn.

Suvojit Dasgupta is a Sr. Lakehouse Architect at Amazon Web Services. He works with customers to design and build data solutions on AWS.

Justin Kuskowski is a Principal DevOps Consultant at Amazon Web Services. He works directly with AWS customers to provide guidance and technical assistance around improving their value stream, which ultimately reduces product time to market and leads to a better customer experience. Outside of work, Justin enjoys traveling the country to watch his two kids play soccer and spending time with his family and friends wake surfing on the lakes in Michigan.

Using CloudFormation events to build custom workflows for post provisioning management

Post Syndicated from Vivek Kumar original https://aws.amazon.com/blogs/devops/using-cloudformation-events-to-build-custom-workflows-for-post-provisioning-management/

Over one million active customers manage application resources with AWS CloudFormation every week. CloudFormation is a service that helps you model, provision, and manage your cloud resources by treating Infrastructure as Code (IaC). It can simplify infrastructure management, quickly replicate your environment to multiple AWS regions with a single turn-key solution, and let you easily control and track changes in your infrastructure.

You can create various AWS resources using CloudFormation to setup an environment for your workloads. You continue to interact with and manage those resources throughout the workload lifecycle to make sure the resource configuration is aligned with business objectives such as adhering to security compliance standards, meeting required reliability targets, and aligning with budget requirements. The inability to perform a hand-off between resource provisioning actions in CloudFormation and resource management actions in other relevant AWS and non-AWS services poses a challenge. For example, after provisioning of resources, customers might need to perform additional tasks to manage these resources such as adding cost allocation tags, populating resource inventory database or trigger downstream processes.

While they are able to obtain the logical resource grouping that is tied to a workload or a workload component with a CloudFormation stack, that context does not extend beyond CloudFormation for the most part when they use various AWS and non-AWS services to conduct post-provisioning resource management. These AWS and non-AWS services typically offer a resource level view, or in some cases offer basic aggregated views such as supporting a tag group, or an account level abstraction to see all resources in a given account. For a CloudFormation customer, the inability to not have the context of a stack beyond resource provisioning provides a disjointed experience given there is no hand-off between resource provisioning actions in CloudFormation and resource management actions in other relevant AWS and non-AWS services. The various management actions customers take with their workload resources through out their lifecycle are

CloudFormation events provide a robust way to track the status of individual resources during the lifecycle of a stack. You can send CloudFormation events to Amazon EventBridge whenever a create, update,  or drift detection action is performed on your stack. Then you can set up additional workflows based on those events from EventBridge. For example, by tagging the resources automatically, you can reference that tag group when using AWS Trusted Advisor, and continue your resource management experience post-provisioning. CloudFormation sends these events to EventBridge automatically so that you don’t need to do anything. One real-world use case is to use these events to create actionable tasks for your teams to troubleshoot issues. CloudFormation events published to EventBridge can be used to create OpsItems within AWS Systems Manager OpsCenter. OpsItems are the work items created in OpsCenter for engineers to view, investigate and remediate tasks/issues. This enables teams to respond and resolve any issues more efficiently.

Walkthrough

To set up the EventBridge rule, go to the AWS console and navigate to EventBridge. Select on Create Rule to get started. Enter Name, description and select Next:

Create Rule

On the next screen, select AWS events in the Event source section.

This sample event is for the CREATE_COMPLETE event. It contains the source, AWS account number, AWS region, event type, resources and details about the event.

On the same page in the Event pattern section:

Select Custom patterns (JSON editor) and enter the following event pattern. This will match any events when a resource fails to create, update, or delete. Learn more about EventBridge event patterns.

{
    "source": [
        "aws.cloudformation"
    ],
    "detail-type": [
        "CloudFormation Resource Status Change"
    ],
    "detail": {
        "status-details": {
            "status": [
                "CREATE_FAILED",
                "UPDATE_FAILED",
                "DELETE_FAILED"
            ]
        }
    }
}

Custom patterns - JSON editor

Select Next. On the Target screen, select AWS service, then select System Manager OpsItem as the target for this rule.

Target 1

Add a second target – an Amazon Simple Notification Service (SNS) Topic – to notify the Ops team whenever a failure occurs and an OpsItem has been created.

Target 2

Select Next and optionally add tags.

Select next to review the selections, and select Create rule.

Now your rule is created and whenever a stack failure occurs, an OpsItem gets created and a notification is sent out for the operators to troubleshoot and fix the issue. The OpsItem contains operational data, such as the resource that failed, the reason for failure, as well as the stack to which it belongs, which is useful for troubleshooting the issue. Operators can take manual actions or use runbooks codified as Systems Manager Documents to take corrective actions. From the AWS Console you can go to OpsCenter to see the events:

operational data

Once the issues have been addressed, operators can mark the OpsItem as resolved, and retry the stack operation that failed, resulting in a swift resolution of the issue, and preventing duplication of efforts.

This walkthrough is for the Console but you can use AWS Command Line Interface (AWS CLI), AWS SDK or even CloudFormation to accomplish all of this. Refer to AWS CLI documentation for more information on creating EventBridge rules through CLI. Furthermore, refer to AWS SDK documentation for creating EventBridge rules through AWS SDK. You can use following CloudFormation template to deploy the EventBridge rules example used as part of the walkthrough in this blog post:

{
	"Parameters": {
		"SNSTopicARN": {
			"Type": "String",
			"Description": "Enter the ARN of the SNS Topic where you want stack failure notifications to be sent."
		}
	},
	"Resources": {
		"CFNEventsRule": {
			"Type": "AWS::Events::Rule",
			"Properties": {
				"Description": "Event rule to capture CloudFormation failure events",
				"EventPattern": {
					"source": [
						"aws.cloudformation"
					],
					"detail-type": [
						"CloudFormation Resource Status Change"
					],
					"detail": {
						"status-details": {
							"status": [
								"CREATE_FAILED",
								"UPDATE_FAILED",
								"DELETE_FAILED"
							]
						}
					}
				},
				"Name": "cfn-stack-failure-test",
				"State": "ENABLED",
				"Targets": [
					{
						"Arn": {
							"Fn::Sub": "arn:aws:ssm:${AWS::Region}:${AWS::AccountId}:opsitem"
						},
						"Id": "opsitems",
						"RoleArn": {
							"Fn::GetAtt": [
								"TargetInvocationRole",
								"Arn"
							]
						}
					},
					{
						"Arn": {
							"Ref": "SNSTopicARN"
						},
						"Id": "sns"
					}
				]
			}
		},
		"TargetInvocationRole": {
			"Type": "AWS::IAM::Role",
			"Properties": {
				"AssumeRolePolicyDocument": {
					"Version": "2012-10-17",
					"Statement": [
						{
							"Effect": "Allow",
							"Principal": {
								"Service": [
									"events.amazonaws.com"
								]
							},
							"Action": [
								"sts:AssumeRole"
							]
						}
					]
				},
				"Path": "/",
				"Policies": [
					{
						"PolicyName": "createopsitem",
						"PolicyDocument": {
							"Version": "2012-10-17",
							"Statement": [
								{
									"Effect": "Allow",
									"Action": [
										"ssm:CreateOpsItem"
									],
									"Resource": "*"
								}
							]
						}
					}
				]
			}
		},
		"AllowSNSPublish": {
			"Type": "AWS::SNS::TopicPolicy",
			"Properties": {
				"PolicyDocument": {
					"Statement": [
						{
							"Sid": "grant-eventbridge-publish",
							"Effect": "Allow",
							"Principal": {
								"Service": "events.amazonaws.com"
							},
							"Action": [
								"sns:Publish"
							],
							"Resource": {
								"Ref": "SNSTopicARN"
							}
						}
					]
				},
				"Topics": [
					{
						"Ref": "SNSTopicARN"
					}
				]
			}
		}
	}
}

Summary

Responding to CloudFormation stack events becomes easy with the integration between CloudFormation and EventBridge. CloudFormation events can be used to perform post-provisioning actions on workload resources. With the variety of targets available to EventBridge rules, various actions such as adding tags and, troubleshooting issues can be performed. This example above uses Systems Manager and Amazon SNS but you can have numerous targets including, Amazon API gateway, AWS Lambda, Amazon Elastic Container Service (Amazon ECS) task, Amazon Kinesis services, Amazon Redshift, Amazon SageMaker pipeline, and many more. These events are available for free in EventBridge.

Learn more about Managing events with CloudFormation and EventBridge.

About the Author

Vivek is a Solutions Architect at AWS based out of New York. He works with customers providing technical assistance and architectural guidance on various AWS services. He brings more than 25 years of experience in software engineering and architecture roles for various large-scale enterprises.


Mahanth is a Solutions Architect at Amazon Web Services (AWS). As part of the AWS Well-Architected team, he works with customers and AWS Partner Network partners of all sizes to help them build secure, high-performing, resilient, and efficient infrastructure for their applications. He spends his free time playing with his pup Cosmo, learning more about astronomy, and is an avid gamer.


Sukhchander is a Solutions Architect at Amazon Web Services. He is passionate about helping startups and enterprises adopt the cloud in the most scalable, secure, and cost-effective way by providing technical guidance, best practices, and well architected solutions.