AI 101: Training vs. Inference

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/ai-101-training-vs-inference/

A decorative image depicting a neural network identifying a cat.

What do Sherlock Holmes and ChatGPT have in common? Inference, my dear Watson!

“We approached the case, you remember, with an absolutely blank mind, which is always an advantage. We had formed no theories. We were simply there to observe and to draw inferences from our observations.”
—Sir Arthur Conan Doyle, The Adventures of the Cardboard Box

As we all continue to refine our thinking around artificial intelligence (AI), it’s useful to define terminology that describes the various stages of building and using AI algorithms—namely, the AI training stage and the AI inference stage. As we see in the quote above, these are not new concepts: they’re based on ideas and methodologies that have been around since before Sherlock Holmes’ time. 

If you’re using AI, building AI, or just curious about AI, it’s important to understand the difference between these two stages so you understand how data moves through an AI workflow. That’s what I’ll explain today.

The TL:DR

The difference between these two terms can be summed up fairly simply: first you train an AI algorithm, then your algorithm uses that training to make inferences from data. To create a whimsical analogy, when an algorithm is training, you can think of it like Watson—still learning how to observe and draw conclusions through inference. Once it’s trained, it’s an inferring machine, a.k.a. Sherlock Holmes. 

Whimsy aside, let’s dig a little deeper into the tech behind AI training and AI inference, the differences between them, and why the distinction is important. 

Obligatory Neural Network Recap

Neural networks have emerged as the brainpower behind AI, and a basic understanding of how they work is foundational when it comes to understanding AI.  

Complex decisions, in theory, can be broken down into a series of yeses and nos, which means that they can be encoded in binary. Neural networks have the ability to combine enough of those smaller decisions, weigh how they affect each other, and then use that information to solve complex problems. And, because more complex decisions require more points of information to come to a final decision, they require more processing power. Neural networks are one of the most widely used approaches to AI and machine learning (ML). 

A diagram showing the inputs, hidden layers, and outputs of a neural network.

What Is AI Training?: Understanding Hyperparameters and Parameters

In simple terms, training an AI algorithm is the process through which you take a base algorithm and then teach it how to make the correct decision. This process requires large amounts of data, and can include various degrees of human oversight. How much data you need has a relationship to the number of parameters you set for your algorithm as well as the complexity of a problem. 

We made this handy dandy diagram to show you how data moves through the training process:

A diagram showing how data moves through an AI training algorithm.
As you can see in this diagram, the end result is model data, which then gets saved in your data store for later use.

And hey—we’re leaving out a lot of nuance in that conversation because dataset size, parameter choice, etc. is a graduate-level topic on its own, and usually is considered proprietary information by the companies who are training an AI algorithm. It suffices to say that dataset size and number of parameters are both significant and have a relationship to each other, though it’s not a direct cause/effect relationship. And, both the number of parameters and the size of the dataset affect things like processing resources—but that conversation is outside of scope for this article (not to mention a hot topic in research). 

As with everything, your use case determines your execution. Some types of tasks actually see excellent results with smaller datasets and more parameters, whereas others require more data and fewer parameters. Bringing it back to the real world, here’s a very cool graph showing how many parameters different AI systems have. Note that they very helpfully identified what type of task each system is designed to solve:

So, let’s talk about what parameters are with an example. Back in our very first AI 101 post, we talked about ways to frame an algorithm in simple terms: 

Machine learning does not specify how much knowledge the bot you’re training starts with—any task can have more or fewer instructions. You could ask your friend to order dinner, or you could ask your friend to order you pasta from your favorite Italian place to be delivered at 7:30 p.m. 

Both of those tasks you just asked your friend to complete are algorithms. The first algorithm requires your friend to make more decisions to execute the task at hand to your satisfaction, and they’ll do that by relying on their past experience of ordering dinner with you—remembering your preferences about restaurants, dishes, cost, and so on. 

The factors that help your friend make a decision about dinner are called hyperparameters and parameters. Hyperparameters are those that frame the algorithm—they are set  outside the training process, but can influence the training of the algorithms. In the example above, a hyperparameter would be how you structure your dinner feedback. Do you thumbs up or down each dish? Do you write a short review? You get the idea. 

Parameters are factors that the algorithm derives through training. In the example above, that’s what time you prefer to eat dinner, which restaurants you enjoy after eating, and so on. 

When you’ve trained a neural network, there will be heavier weights between various nodes. That’s a shorthand of saying that an algorithm will prefer a path it knows is significant, and if you want to really get nerdy with it, this article is well-researched, has a ton of math explainers for various training methods, and includes some fantastic visuals. For our purposes, here’s one way people visualize a “trained” algorithm: 

An image showing a neural network that has prioritized certain pathways after training.
Source.

The “dropout method” is essentially adding weight to the relationships an AI algorithm has found to be significant for the dataset it’s working on. It can then de-prioritize (or sometimes even eliminate) the other relationships. 

Once you have a trained algorithm, then you can use it with a reasonable degree of certainty that it will give you good results, and that leads us to inference. 

What Is AI Inference?

Once you’ve trained your algorithm, you can send it out in the world to do its job (and make yours easier). When you present a trained AI algorithm with a problem and it gives you an answer, that’s called inference. It’s using the way it was trained to draw conclusions or make predictions, depending on how it was built, and once an algorithm is in the “inference stage”, it’s no longer learning (usually). 

Here’s our diagram for how data might move through an inference process: 

A diagram showing how data moves through an inference workflow.
As you can see, if we want to add more training data to the algorithm, we’d do so as a separate input/output flow. The goal of this process is to output data.

As we’ve seen in the real world, this does not mean that the AI model will give you a perfect answer every time—depending on, for example, the AI’s access to new or current information, the complexity of training, etc., the algorithm might give you a better or worse (more or less accurate) answer. But, it will be able to look at a new piece of information or dataset, and return a response. 

When I asked our friend ChatGPT about this, it broke down inference and defined it in relation to the logical underpinnings of different types of algorithms. (As a mere human, how could I resist using inference while writing about inference?) Sure, ChatGPT may be merely mimicking human-like dialogue based on its ingestion of the whole internet, then giving me the most likely answer based on its specialized neural network that predicts the likelihood of the next word in response to my conversational query and without access to data after January 2022, but here’s what our AI friend had to say for itself: 

  • Machine Learning Inference: In machine learning, after a model has been trained on a dataset, it is deployed to make predictions or classifications on new, unseen data. During inference, the model takes the input data, processes it, and produces an output or a prediction based on the patterns and relationships it learned during training. For example, a trained machine learning model might be used to classify images, predict stock prices, or identify spam emails.
  • Deep Learning Inference: Deep learning, a subfield of machine learning, involves neural networks with multiple layers. In deep learning, inference means feeding an input through a trained deep neural network and obtaining an output. This is commonly used in applications like image recognition, natural language processing, and speech recognition. Inference in deep learning can be computationally intensive, and specialized hardware, such as GPUs and TPUs, are often used to accelerate the process.
  • Rule-Based Systems Inference: In rule-based AI systems, inference is the process of applying logical rules to make decisions or draw conclusions. These systems use a set of predefined rules and facts to reason and infer new information. For example, in an expert system for medical diagnosis, inference involves applying a set of rules to patient symptoms and medical knowledge to arrive at a diagnosis.
  • Probabilistic Inference: In probabilistic AI, inference is used to estimate probabilities and uncertainty. Bayesian networks and Markov decision processes are examples of probabilistic models that perform inference to compute probabilities of events or make decisions based on probabilities.

You’ll notice that each of these are saying basically the same thing: the AI algorithm applies its decision-making paradigm to a problem. 

Why Stop Learning During the Inference Stage?

In general, it’s important to keep these two stages—training and inference—of an AI algorithm separate for a few reasons: 

  • Efficiency: Training is typically a computationally intensive process, whereas inference is usually faster and less resource-intensive. Separating them allows for efficient use of computational resources.
  • Generalization: The model’s ability to generalize from training data to unseen data is a key feature. It should not learn from every new piece of data it encounters during inference to maintain this generalization ability.
  • Reproducibility: When using trained models in production or applications, it’s important to have consistency and reproducibility in the results. If models were allowed to learn during inference, it would introduce variability and unpredictability in their behavior.

There are some specialized AI algorithms that want to continue learning during the inference stage—your Netflix algorithm is a good example, as are self-driving cars, or dynamic pricing models used to set airfare pricing. On the other hand, the majority of problems we’re trying to solve with AI algorithms deliver better decisions by separating these two phases—think of things like image recognition, language translation, or medical diagnosis, for example.

Training vs. Inference (But, Really: Training Then Inference)

To recap: the AI training stage is when you feed data into your learning algorithm to produce a model, and the AI inference stage is when your  algorithm uses that training to make inferences from data. Here’s a chart for quick reference: 

Training Inference
Feed training data into a learning algorithm. Apply the model to inference data.
Produces a model comprising code and data. Produces output data.
One time(ish). Retraining is sometimes necessary. Often continuous.

The difference may seem inconsequential at first glance, but defining these two stages helps to show implications for AI adoption particularly with businesses. That is, given that it’s much less resource intensive (and therefore, less expensive), it’s likely to be much easier for businesses to integrate already-trained AI algorithms with their existing systems. 

And, as always, we’re big believers in demystifying terminology for discussion purposes. Let us know what you think in the comments, and feel free to let us know what you’re interested in learning about next.

The post AI 101: Training vs. Inference appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
Create a modern data platform using the Data Build Tool (dbt) in the AWS Cloud

Post Syndicated from Prantik Gachhayat original https://aws.amazon.com/blogs/big-data/create-a-modern-data-platform-using-the-data-build-tool-dbt-in-the-aws-cloud/

Building a data platform involves various approaches, each with its unique blend of complexities and solutions. A modern data platform entails maintaining data across multiple layers, targeting diverse platform capabilities like high performance, ease of development, cost-effectiveness, and DataOps features such as CI/CD, lineage, and unit testing. In this post, we delve into a case study for a retail use case, exploring how the Data Build Tool (dbt) was used effectively within an AWS environment to build a high-performing, efficient, and modern data platform.

dbt is an open-source command line tool that enables data analysts and engineers to transform data in their warehouses more effectively. It does this by helping teams handle the T in ETL (extract, transform, and load) processes. It allows users to write data transformation code, run it, and test the output, all within the framework it provides. dbt enables you to write SQL select statements, and then it manages turning these select statements into tables or views in Amazon Redshift.

Use case

The Enterprise Data Analytics group of a large jewelry retailer embarked on their cloud journey with AWS in 2021. As part of their cloud modernization initiative, they sought to migrate and modernize their legacy data platform. The aim was to bolster their analytical capabilities and improve data accessibility while ensuring a quick time to market and high data quality, all with low total cost of ownership (TCO) and no need for additional tools or licenses.

dbt emerged as the perfect choice for this transformation within their existing AWS environment. This popular open-source tool for data warehouse transformations won out over other ETL tools for several reasons. dbt’s SQL-based framework made it straightforward to learn and allowed the existing development team to scale up quickly. The tool also offered desirable out-of-the-box features like data lineage, documentation, and unit testing. A crucial advantage of dbt over stored procedures was the separation of code from data—unlike stored procedures, dbt doesn’t store the code in the database itself. This separation further simplifies data management and enhances the system’s overall performance.

Let’s explore the architecture and learn how to build this use case using AWS Cloud services.

Solution overview

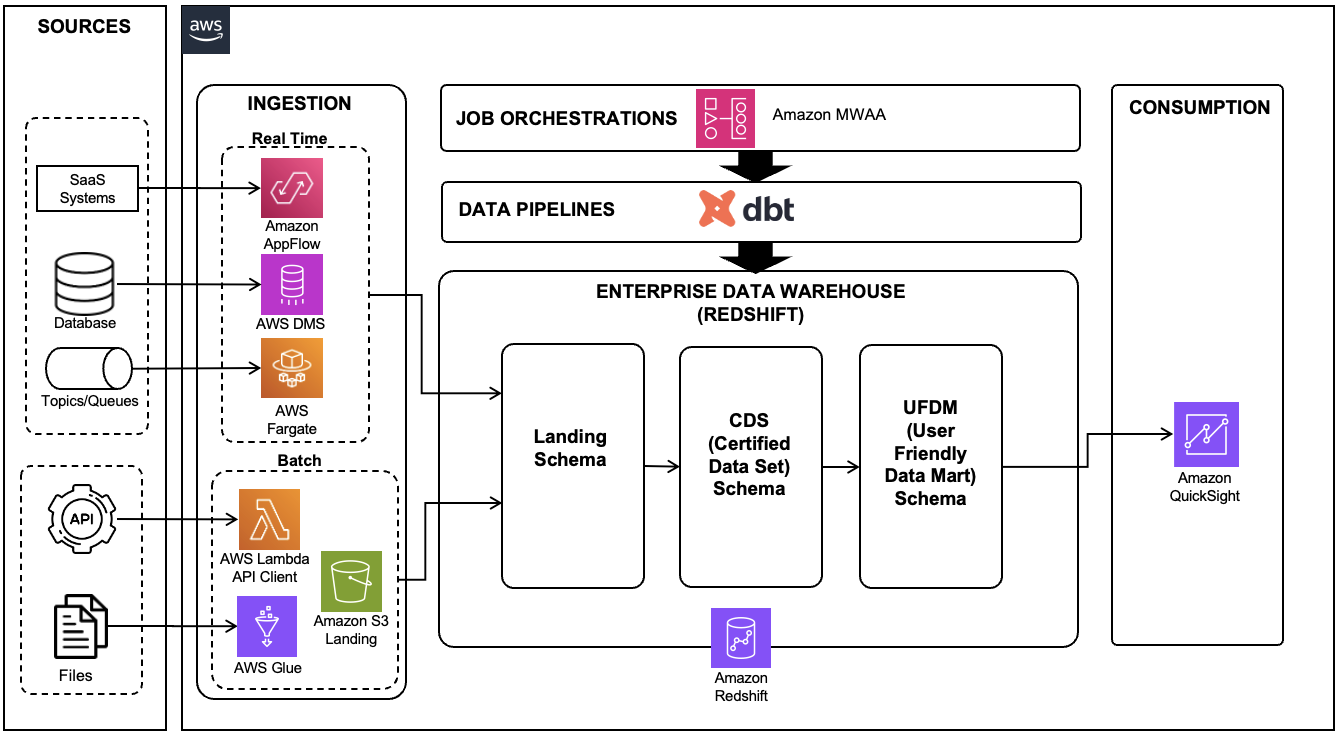
The following architecture demonstrates the data pipeline built on dbt to manage the Redshift data warehouse ETL process.

        Figure 1 : Modern data platform using AWS Data Services and dbt

This architecture consists of the following key services and tools:

  • Amazon Redshift was utilized as the data warehouse for the data platform, storing and processing vast amounts of structured and semi-structured data
  • Amazon QuickSight served as the business intelligence (BI) tool, allowing the business team to create analytical reports and dashboards for various business insights
  • AWS Database Migration Service (AWS DMS) was employed to perform change data capture (CDC) replication from various source transactional databases
  • AWS Glue was put to work, loading files from the SFTP location to the Amazon Simple Storage Service (Amazon S3) landing bucket and subsequently to the Redshift landing schema
  • AWS Lambda functioned as a client program, calling third-party APIs and loading the data into Redshift tables
  • AWS Fargate, a serverless container management service, was used to deploy the consumer application for source queues and topics
  • Amazon Managed Workflows for Apache Airflow (Amazon MWAA) was used to orchestrate different tasks of dbt pipelines
  • dbt, an open-source tool, was employed to write SQL-based data pipelines for data stored in Amazon Redshift, facilitating complex transformations and enhancing data modeling capabilities

Let’s take a closer look at each component and how they interact in the overall architecture to transform raw data into insightful information.

Data sources

As part of this data platform, we are ingesting data from diverse and varied data sources, including:

  • Transactional databases – These are active databases that store real-time data from various applications. The data typically encompasses all transactions and operations that the business engages in.
  • Queues and topics – Queues and topics come from various integration applications that generate data in real time. They represent an instantaneous stream of information that can be used for real-time analytics and decision-making.
  • Third-party APIs – These provide analytics and survey data related to ecommerce websites. This could include details like traffic metrics, user behavior, conversion rates, customer feedback, and more.
  • Flat files – Other systems supply data in the form of flat files of different formats. These files, stored in an SFTP location, might contain records, reports, logs, or other kinds of raw data that can be further processed and analyzed.

Data ingestion

Data from various sources are grouped into two major categories: real-time ingestion and batch ingestion.

Real-time ingestion uses the following services:

  • AWS DMS – AWS DMS is used to create CDC replication pipelines from OLTP (Online Transaction Processing) databases. The data is loaded into Amazon Redshift in near-real time to ensure that the most recent information is available for analysis. You can also use Amazon Aurora zero-ETL integration with Amazon Redshift to ingest data directly from OLTP databases to Amazon Redshift.
  • Fargate –Fargate is used to deploy Java consumer applications that ingest data from source topics and queues in real time. This real-time data consumption can help the business make immediate and data-informed decisions. You can also use Amazon Redshift Streaming Ingestion to ingest data from streaming engines like Amazon Kinesis Data Streams or Amazon Managed Streaming for Apache Kafka (Amazon MSK) into Amazon Redshift.

Batch ingestion uses the following services:

  • Lambda – Lambda is used as a client for calling third-party APIs and loading the resultant data into Redshift tables. This process has been scheduled to run daily, ensuring a consistent batch of fresh data for analysis.
  • AWS Glue – AWS Glue is used to load files into Amazon Redshift through the S3 data lake. You can also use features like auto-copy from Amazon S3 (feature under preview) to ingest data from Amazon S3 to Amazon Redshift. However, the focus of this post is more on data processing within Amazon Redshift, rather than on the data loading process. Data ingestion, whether real time or batch, forms the basis of any effective data analysis, enabling organizations to gather information from diverse sources and use it for insightful decision-making.

Data warehousing using Amazon Redshift

In Amazon Redshift, we’ve established three schemas, each serving as a different layer in the data architecture:

  • Landing layer – This is where all data ingested by our services initially lands. It’s raw, unprocessed data straight from the source.
  • Certified dataset (CDS) layer – This is the next stage, where data from the landing layer undergoes cleaning, normalization, and aggregation. The cleansed and processed data is stored in this certified dataset schema. It serves as a reliable, organized source for downstream data analysis.
  • User-friendly data mart (UFDM) layer – This final layer uses data from the CDS layer to create data mart tables. These are specifically tailored to support BI reports and dashboards as per the business requirements. The goal of this layer is to present the data in a way that is most useful and accessible for end-users.

This layered approach to data management allows for efficient and organized data processing, leading to more accurate and meaningful insights.

Data pipeline

dbt, an open-source tool, can be installed in the AWS environment and set up to work with Amazon MWAA. We store our code in an S3 bucket and orchestrate it using Airflow’s Directed Acyclic Graphs (DAGs). This setup facilitates our data transformation processes in Amazon Redshift after the data is ingested into the landing schema.

To maintain modularity and handle specific domains, we create individual dbt projects. The nature of the data reporting—real-time or batch—affects how we define our dbt materialization. For real-time reporting, we define materialization as a view, loading data into the landing schema using AWS DMS from database updates or from topic or queue consumers. For batch pipelines, we define materialization as a table, allowing data to be loaded from various types of sources.

In some instances, we have had to build data pipelines that extend from the source system all the way to the UFDM layer. This can be accomplished using Airflow DAGs, which we discuss further in the next section.

To wrap up, it’s worth mentioning that we deploy a dbt webpage using a Lambda function and enable a URL for this function. This webpage serves as a hub for documentation and data lineage, further bolstering the transparency and understanding of our data processes.

ETL job orchestration

In our data pipeline, we follow these steps for job orchestration:

  1. Establish a new Amazon MWAA environment. This environment serves as the central hub for orchestrating our data pipelines.
  2. Install dbt in the new Airflow environment by adding the following dependency to your requirements.txt:
    boto3>=1.17.54
    botocore>=1.20.54
    dbt-redshift>=1.3.0
    dbt-postgres>=1.3.0

  3. Develop DAGs with specific tasks that call upon dbt commands to carry out the necessary transformations. This step involves structuring our workflows in a way that captures dependencies among tasks and ensures that tasks run in the correct order. The following code shows how to define the tasks in the DAG:
    #imports..
    ...
    
    #Define the begin_exec tasks
    start = DummyOperator(
        task_id='begin_exec',
        dag=dag 
    )
    
    #Define 'verify_dbt_install' task to check if dbt was installed properly
    verify = BashOperator(
        task_id='verify_dbt_install',
        dag=dag,
        bash_command='''
            echo "checking dbt version....";             
            /usr/local/airflow/.local/bin/dbt --version;
            if [ $? -gt 0 ]; then
                pip install dbt-redshift>=1.3.0;
            else
                echo "dbt already installed";
            fi
            python --version;
            echo "listing dbt...";      
            rm -r /tmp/dbt_project_home;
            cp -R /usr/local/airflow/dags/dbt_project_home /tmp;
            ls /tmp/dbt_project_home/<your_dbt_project_name>;
        '''
    )
    
    #Define ‘landing_to_cds_task’ task to copy from landing schema to cds schema
    landing_to_cds_task = BashOperator(
        task_id='landing_to_cds_task', 
        dag = dag,
        bash_command='''        
            /usr/local/airflow/.local/bin/dbt run --project-dir /tmp/dbt_project_home/<your_dbt_project_name> --profiles-dir /tmp/dbt_project_home/ --select <model_folder_name>.*;
        '''
    )
    
    ...
    #Define data quality check task to test a package, generate docs and copy the docs to required S3 location
    data_quality_check = BashOperator(
        task_id='data_quality_check',
        dag=dag,
        bash_command='''    
       	  /usr/local/airflow/.local/bin/dbt test –-select your_package.*               
            /usr/local/airflow/.local/bin/dbt docs generate --project-dir /tmp/dbt_project_home/<your_project_name> --profiles-dir /tmp/dbt_project_home/;        
            aws s3 cp /tmp/dbt_project_home/<your_project_name>/target/ s3://<your_S3_bucket_name>/airflow_home/dags/dbt_project_home/<your_project_name>/target --recursive;
        '''
    )

  4. Create DAGs that solely focus on dbt transformation. These DAGs handle the transformation process within our data pipelines, harnessing the power of dbt to convert raw data into valuable insights.
    #This is how we define the flow 
    start >> verify >> landing_to_cds_task >> cds_to_ufdm_task >> data_quality_check >> end_exec

The following image shows how this workflow would be seen on the Airflow UI .

  1. Create DAGs with AWS Glue for ingestion. These DAGs use AWS Glue for data ingestion tasks. AWS Glue is a fully managed ETL service that makes it easy to prepare and load data for analysis. We create DAGs that orchestrate AWS Glue jobs for extracting data from various sources, transforming it, and loading it into our data warehouse.
          #Create boto3 client for Glue 
          glue_client = boto3.client('glue', region_name='us-east-1')
    
          #Define callback function to start the Glue job using boto3 client 
          def run_glue_ingestion_job():
       glue_client.start_job_run(JobName='glue_ingestion_job')  
    
    #Define the task for glue job for ingestion
       glue_job_step = PythonOperator(
           task_id=’glue_task_for_source_to_landing’, 
           python_callable=run_glue_ingestion_job
       )
    #This is how we define the flow 
    start >> verify >> glue_task_for_source_to_landing >> landing_to_cds_task >> cds_to_ufdm_task >> data_quality_check >> end_exec
    

The following image shows how this workflow would be seen on the Airflow UI.

  1. Create DAGs with Lambda for ingestion. Lambda lets us run code without provisioning or managing servers. These DAGs use Lambda functions to call third-party APIs and load data into our Redshift tables, which can be scheduled to run at certain intervals or in response to specific events.
    #Create boto3 client for Lambda 
    lambda_client = boto3.client('lambda')
    
    #Define callback function to invoke the lambda function using boto3 client 
    def run_lambda_ingestion_job():
       Lambda_client.invoke(FunctionName='<funtion_arn>')
    )  
    
    #Define the task for glue job for ingestion
    glue_job_step = PythonOperator(
       task_id=’lambda_task_for_api_to_landing’, 
       python_callable=run_lambda_ingestion_job
    )

The following image shows how this workflow would be seen on the Airflow UI.

We now have a comprehensive, well-orchestrated process that uses a variety of AWS services to handle different stages of our data pipeline, from ingestion to transformation.

Conclusion

The combination of AWS services and the dbt open-source project provides a powerful, flexible, and scalable solution for building modern data platforms. It’s a perfect blend of manageability and functionality, with its easy-to-use, SQL-based framework and features like data quality checks, configurable load types, and detailed documentation and lineage. Its principles of “code separate from data” and reusability make it a convenient and efficient tool for a wide range of users. This practical use case of building a data platform for a retail organization demonstrates the immense potential of AWS and dbt for transforming data management and analytics, paving the way for faster insights and informed business decisions.

For more information about using dbt with Amazon Redshift, see Manage data transformations with dbt in Amazon Redshift.


About the Authors

Prantik Gachhayat is an Enterprise Architect at Infosys having experience in various technology fields and business domains. He has a proven track record helping large enterprises modernize digital platforms and delivering complex transformation programs. Prantik specializes in architecting modern data and analytics platforms in AWS. Prantik loves exploring new tech trends and enjoys cooking.

Ashutosh Dubey is a Senior Partner Solutions Architect and Global Tech leader at Amazon Web Services based out of New Jersey, USA. He has extensive experience specializing in the Data and Analytics and AIML field including generative AI, contributed to the community by writing various tech contents, and has helped Fortune 500 companies in their cloud journey to AWS.

AWS CodeBuild adds support for AWS Lambda compute mode

Post Syndicated from Ryan Bachman original https://aws.amazon.com/blogs/devops/aws-codebuild-adds-support-for-aws-lambda-compute-mode/

AWS CodeBuild recently announced that it supports running projects on AWS Lambda. AWS CodeBuild is a fully managed continuous integration (CI) service that allows you to build and test your code without having to manage build servers. This new compute mode enables you to execute your CI process on the same AWS Lambda base images supported by the AWS Lambda service, providing consistency, performance, and cost benefits. If you are already building and deploying microservices or building code packages, its likely these light-weight and smaller code bases will benefit from the efficiencies gained by using Lambda compute for CI. In this post, I will explain the benefits of this new compute mode as well as provide an example CI workflow to demonstrate these benefits.

Consistency Benefits

One of the key benefits of running AWS CodeBuild projects using the AWS Lambda compute mode is consistency. By building and testing your serverless applications on the same base images AWS Lambda provides, you can ensure that your application works as intended before moving to production. This eliminates the possibility of compatibility issues that may arise when deploying to a different environment. Moreover, because the AWS Lambda runtime provides a standardized environment across all regions, you can build your serverless applications in Lambda on CodeBuild and have the confidence to deploy to any region where your customers are located.

Performance and Cost Benefits

Another significant advantage of running AWS CodeBuild projects on the AWS Lambda compute mode is performance. When you run your project with EC2 compute mode, there may be increased start-up latency that impacts the total CI process.  However, because AWS Lambda is designed to process events in near real-time, executing jobs on the AWS Lambda compute mode can result in significant time savings. As a result, by switching to this new compute mode, you save time within your CI process and increase your frequency of integration.

Related to performance, our customers are looking for opportunities to optimize cost and deliver business value at the lowest price point. Customers can see meaningful cost optimization when using Lambda. Lambda-based compute offers better price/performance than CodeBuild’s current Amazon Elastic Compute Cloud (Amazon EC2) based compute — with per-second billing, 6,000 seconds of free tier, and 10GB of ephemeral storage. CodeBuild supports both x86 and Arm using AWS Graviton Processors for the new compute mode. By using the Graviton option, customers can further achieve lower costs with better performance.

Considerations

There are a few things to consider before moving your projects to AWS Lambda compute mode. Because this mode utilizes the same AWS Lambda service used by customers, there is a maximum project duration of 15 minutes and custom build timeouts are not supported. Additionally, local caching, batch builds, and docker image builds are not supported with Lambda compute mode. For a full list of limitations please refer to the AWS CodeBuild User Guide.

Walk-Through

In this walk-through I used a simple React app to showcase the performance benefits of building using CodeBuild’s Lambda compute option. To get started, I created an AWS CodeCommit repository and used npm to create a sample application that I then pushed to my CodeCommit repo.

CodeCommit repository for react code

Figure 1: CodeCommit Repository

Once my sample application is stored in my code repository, I then navigated to the AWS CodeBuild console. Using the console, I created two different CodeBuild projects. I selected my CodeCommit repository for the projects’ source and selected EC2 compute for one and Lambda for the other.

CodeBuild compute mode options

Figure 2: CodeBuild compute mode options

The compute mode is independent from instructions included in the project’s buildspec.yaml, so in order to test and compare the CI job on the two different compute modes, I created a buildspec and pushed that to the CodeCommit repository where I stored my simple React app in the previous step.

buildspec.yaml
version: 0.2
phases:
  build:
    commands:
      - npm install -g yarn
      - yarn
      - npm run build
      - npm run test -- --coverage --watchAll=false --testResultsProcessor="jest-junit"
artifacts:
  name: "build-output"
  base-directory: 'react-app'
  files:
    - "**/*"
reports:
  test-report:
    base-directory: 'react-app'
    files:
      - 'junit.xml'
    file-format: 'JUNITXML'
  coverage-report:
    base-directory: 'react-app'
    files:
      - 'coverage/clover.xml'
    file-format: 'CLOVERXML'

Once my projects were ready, I manually started each project from the console. Below are screenshots of the details of the execution times for each.

EC2 compute mode details

Figure 3: EC2 compute mode details

Lambda Compute mode details

Figure 4: Lambda compute mode details

If you compare the provisioning and build times for this example you will see that the Lambda CodeBuild project executed significantly faster. In this example, the Lambda option was over 50% faster than the same build executed on EC2. If you are frequently building similar microservices that can take advantage of these efficiency gains, it is likely that CodeBuild on Lambda can save you both time and cost in your CI/CD pipelines.

Cleanup

If you followed along the walkthrough, you will want to remove the resources you created. First delete the two projects created in CodeBuild. This can be done by navigating to CodeBuild in the console, selecting each project and then hitting the “Delete build project” button. Next navigate to CodeCommit and delete the repository where you stored the code.

Conclusion

In conclusion, AWS CodeBuild using Lambda compute-mode provides significant benefits in terms of consistency, performance and cost. By building and testing your applications on the same runtime images executed by the AWS Lambda service, you can take advantage of benefits provided by the AWS Lambda service while reducing CI time and costs. We are excited to see how this new feature will help you build and deploy your applications faster and more efficiently. Get started today and take advantage of the benefits of running AWS CodeBuild projects on the AWS Lambda compute mode.

About the Author:
Ryan Bachman profile image

Ryan Bachman

Ryan Bachman is a Sr. Specialist Solutions Architect with Amazon Web Services (AWS) with a focus on DevOps. Ryan is passionate about helping customers adopt process and services that increase their efficiency developing applications for the cloud. He has over 20 years professional experience as a technologist, including roles in development, network architecture, and technical product management.

[$] The push to save Itanium

Post Syndicated from corbet original https://lwn.net/Articles/950466/

It is (relatively) easy to add code to the kernel; it tends to be much
harder to remove that code later. The most recent example of this dynamic
can be seen in the story of the ia64 (“Itanium”) architecture, support for
which was removed during the 6.7 merge window. That removal has left a
small group of dedicated ia64 users unhappy and clinging to a faint hope
that this support could return in a year’s time.

NEW RESEARCH: Artificial intelligence and Machine Learning Can Be Used to Stop DAST Attacks Before they Start

Post Syndicated from Tom Caiazza original https://blog.rapid7.com/2023/11/09/artificial-intelligence-and-machine-learning-can-be-used-to-stop-dast-attacks-before-they-start/

NEW RESEARCH: Artificial intelligence and Machine Learning Can Be Used to Stop DAST Attacks Before they Start

Within cloud security, one of the most prevalent tools is dynamic application security testing, or DAST. DAST is a critical component of a robust application security framework, identifying vulnerabilities in your cloud applications either pre or post deployment that can be remediated for a stronger security posture.

But what if the very tools you use to identify vulnerabilities in your own applications can be used by attackers to find those same vulnerabilities? Sadly, that’s the case with DASTs. The very same brute-force DAST techniques that alert security teams to vulnerabilities can be used by nefarious outfits for that exact purpose.

There is good news, however. A new research paper written by Rapid7’s Pojan Shahrivar and Dr. Stuart Millar and published by the Institute of Electrical and Electronics Engineers (IEEE) shows how artificial intelligence (AI) and machine learning (ML) can be used to thwart unwanted brute-force DAST attacks before they even begin. The paper Detecting Web Application DAST Attacks with Machine Learning was presented yesterday to the specialist AI/ML in Cybersecurity workshop at the 6th annual IEEE Dependable and Secure Computing conference, hosted this year at the University of Southern Florida (USF) in Tampa.

The team designed and evaluated AI and ML techniques to detect brute-force DAST attacks during the reconnaissance phase, effectively preventing 94% of DAST attacks and eliminating the entire kill-chain at the source. This presents security professionals with an automated way to stop DAST brute-force attacks before they even start. Essentially, AI and ML are being used to keep attackers from even casing the joint in advance of an attack.

This novel work is the first application of AI in cloud security to automatically detect brute-force DAST reconnaissance with a view to an attack. It shows the potential this technology has in preventing attacks from getting off the ground, plus it enables significant time savings for security administrators and lets them complete other high-value investigative work.

Here’s how it is done: Using a real-world dataset of millions of events from enterprise-grade apps, a random forest model is trained using tumbling windows of time to generate aggregated event features from source IPs. In this way the characteristics of a DAST attack related to, for example, the number of unique URLs visited per IP or payloads per session, is learned by the model. This avoids the conventional threshold approach, which is brittle and causes excessive false positives.

This is not the first time Millar and team have made major advances in the use of AI and ML to improve the effectiveness of cloud application security. Late last year, Millar published new research at AISec in Los Angeles, the leading venue for AI/ML cybersecurity innovations, into the use of AI/ML to triage vulnerability remediation, reducing false positives by 96%. The team was also delighted to win AISec’s highly coveted Best Paper Award, ahead of the likes of Apple and Microsoft.

A complimentary pre-print version of the paper Detecting Web Application DAST Attacks with Machine Learning is available on the Rapid7 website by clicking here.

CVE-2023-47246: SysAid Zero-Day Vulnerability Exploited By Lace Tempest

Post Syndicated from Caitlin Condon original https://blog.rapid7.com/2023/11/09/etr-cve-2023-47246-sysaid-zero-day-vulnerability-exploited-by-lace-tempest/

CVE-2023-47246: SysAid Zero-Day Vulnerability Exploited By Lace Tempest

On November 8, 2023, IT service management company SysAid disclosed CVE-2023-47426, a zero-day path traversal vulnerability affecting on-premise SysAid servers. According to Microsoft’s threat intelligence team, who said they discovered the vulnerability, it has been exploited in the wild by DEV-0950 (Lace Tempest) in “limited attacks.” In a social media thread published the evening of November 8, Microsoft emphasized that Lace Tempest distributes the Cl0p ransomware, and that exploitation of CVE-2023-47246 is likely to result in ransomware deployment and/or data exfiltration. Lace Tempest is the same threat actor who perpetrated the MOVEit Transfer and GoAnywhere MFT extortion attacks earlier this year.

SysAid’s advisory on CVE-2023-47246 says the attacker “uploaded a WAR archive containing a WebShell and other payloads into the webroot of the SysAid Tomcat web service.” Post-exploitation behavior included deployment of MeshAgent remote administration tooling and GraceWire malware. There are extensive details about the attack chain in the vendor advisory, along with robust indicators of compromise. An employee of technology company Elastic also reported the evening of November 8 that Elastic had observed exploitation in the wild as far back as October 30.

SysAid’s website claims that the company has upwards of 5,000 customers, including a number of large corporations whose logos adorn SysAid’s customer page. Shodan searches for either a specific CSS file or the favicon both return only 416 instances of SysAid exposed to the public internet. (Note that “exposed” does not necessarily imply that those instances are vulnerable.)

Mitigation guidance

CVE-2023-47246 is fixed in version 23.3.36 of SysAid server. Given the potential for ransomware and extortion attacks, organizations with on-premise SysAid servers should apply the vendor-supplied patches on an emergency basis, invoking incident response procedures if possible, and ensure the server is not exposed to the public internet. We also strongly recommend reviewing the indicators of compromise in SysAid’s advisory and examining environments for suspicious activity, though notably, the advisory says the adversaries may cover their tracks by cleaning up logs and artifacts on disk.

Indicators of compromise

SysAid has an extensive list of IOCs and observed attacker behavior in their advisory. Rather than reproducing that here, we urge organizations to use that vendor advisory as their starting source of truth for threat hunting: https://www.sysaid.com/blog/service-desk/on-premise-software-security-vulnerability-notification

Rapid7 has a Velociraptor artifact available to help organizations identify post-exploitation activity related to this zero-day vulnerability:

  • Yara.Process: Targets observed malware and Cobalt Strike via process YARA
  • Disk.Ntfs: Targets known disk IOCs via Windows.ntfs.mft
  • Forensic.Usn: Targets known disk IOCs via USN journal
  • Evtx.Defender: Searches Defender event logs for evidence of associated alerts
  • Evtx.NetworkIOC: Targets known strings of network IOCs in firewall, Sysmon and PowerShell logs

Rapid7 customers

InsightVM and Nexpose customers will be able to assess their exposure to CVE-2023-47246 with an authenticated Windows check expected to ship in today’s (November 9) content release.

InsightIDR and Managed Detection and Response customers have existing detection coverage through Rapid7’s expansive library of detection rules. Rapid7 recommends installing the Insight Agent on all applicable hosts to ensure visibility into suspicious processes and proper detection coverage. Below is a non-exhaustive list of detections that are deployed and will alert on post-exploitation behavior related to this zero-day vulnerability:

  • Attacker Technique – SpoolSV Spawns CMD or PowerShell
  • Attacker Technique – Possible Process Injection
  • Attacker Technique – PowerShell Download Cradles
  • Attacker Tool – CobaltStrike PowerShell Commands
  • Suspicious Network Connection – Destination Address in Cobalt Strike C2 List

Training and Skills Development: The Zabbix Advantage

Post Syndicated from Michael Kammer original https://blog.zabbix.com/training-and-skills-development-the-zabbix-advantage/26873/

At Zabbix, we know that we’ve developed a competitive product. We know it’s very likely the best on the market. Millions of satisfied customers around the world download and use it every day. But that’s not where the story ends.

It’s critical to us that our customers know how to use our product to its full potential in order to get the most value out of it. That’s why we take ongoing training and skills development so seriously, and why we work hard to equip our users with knowledge that’s designed to increase their productivity and performance.

We’ve got years of experience seeing what works and doesn’t work when it comes to showing our users how to get the most out of Zabbix. We’ve learned how to make complicated concepts simple, how to adjust to a wide variety of cultures and learning styles, and how to build courses that create happier, more productive, and more satisfied users.

Let’s take a look at what we’ve identified as 5 of our best training and development practices, and how they help to make sure that the information we present in our training sessions sticks with our users and helps them get as much value from Zabbix as they possibly can.

Perform an effective training and skills development needs analysis

Quality training and skills development begins with a needs analysis. This is a process that organizations use to determine the gap between the current and desired knowledge, skills, and abilities of end users. It typically involves determining the root cause for a training request, identifying the needed outcomes, and uncovering the best learning approach.

An effective needs analysis addresses questions like these:

  • Which of our users need training the most?
  • What kind of training do they require?
  • How can we best design an effective training program for them?
  • What will be the impact of training on their experience with Zabbix?
  • What level of investment and resources will be required to implement an effective training program for them?

At Zabbix, we ask ourselves these questions and many others before creating new training courses or modifying existing ones. We take into account our users’ backgrounds, including their education and work experience. We are always trying to speak to their experiences and offer content in a language that’s easy for them to understand. Our ultimate goal is to make our training sessions feel relevant to everyone, no matter their level of Zabbix experience.

Once we know who we’re speaking to, we can identify the areas where users may be struggling. We focus on what our users are motivated by and what tasks they seem to stumble over the most, and we know that showing users how our training can positively impact their careers will go a long way toward creating a receptive audience for the information we’re presenting.

Build targeted and customized courses

There’s no such thing as one-size-fits-all when it comes to training and skills development. As the world and technology change, knowing which training methods to implement can be a challenge. Businesses, educators, and learners all have unique learning approaches, and tailoring a custom training program creates balance for effective learning experiences.

The Zabbix method is to create a different course for every skill level and potential user of our services, creating an official Zabbix certified training path that guides our users toward the goal of becoming a Zabbix certified expert.

We start by making sure we’ve clearly identified our target audience, so that we can create content that’s relevant and engaging. For example, in our Zabbix Certified Expert and Zabbix Certified Professional courses, we know that users already have a baseline of knowledge, so we don’t need to provide a lot of background or general information. Understanding our audience helps us keep the content concise and to the point.

From there, we focus on structuring our content. For us, this means keeping training and development focused on a single skill level and keeping content short and to the point. Once we have our “big picture” outline, we work with our trainers to plan out the format, key takeaways, and activities.

That brings us to our final point –providing a truly hands-on experience. We know that it’s critical for learners to be able to quickly apply what they’ve been taught, so we include at least one activity per section of a course, allowing learners to put their new skills to the test by performing practical tasks and solving real-life use cases. This approach is borne out by the fact that our labs are consistently rated by students as among their favorite aspects of the training experience.

Provide quality, professional materials

Experience shows that it’s vitally important to focus on providing training materials that are:

  • Professional in appearance AND user-friendly
  • Available before, during, and after class to reinforce the learning process
  • Aligned with the course objectives
  • Easy to access (including print or online options)

Every student who attends a Zabbix course gets the course presentation as well as the lab manual containing the practical tasks and their solutions. When it comes to the presentation, we go to great lengths to make sure we know our learners and write for them, using accessible, approachable language and keeping things simple and to the point at all times.

Have qualified and experienced instructors

Most people don’t recall a lot of details from specific lectures they attended in high school, but it’s very likely that they remember the name of their favorite teacher. Instructors have a massive impact on how adults learn as well.

Effective trainers continuously practice and develop qualities that improve their understanding of what learners and organizations need. They understand that the more they exercise these qualities, the better equipped they’ll be to deliver engaging trainings that create an active learning atmosphere and incorporate current learning trends.

Every Zabbix Certified trainer works with the tool on a daily basis, so they’ve got plenty of hands-on use cases, hacks, workarounds, and shortcuts to share. They understand that a quality training session is a continuous feedback loop between learners and an instructor, so they listen actively and encourage engagement through the use of activities and Q&A sessions throughout our courses.

In addition to their demonstrated knowledge of all things Zabbix, our trainers also bring to the table strong interpersonal skills and a passion for what they do. That’s why nearly all the feedback we receive highlights the expertise and professionalism of our trainers as a high point of the training experience.

Assess training and skills development effectiveness

Training effectiveness measures the impact of training on a learner’s knowledge, skills, and performance. It needs to measure not only what employees learn but how they apply it in their jobs. It should also determine whether the training truly benefits users, while uncovering any issues in the training process that need to be improved.

Zabbix takes a two-track approach to measuring the effectiveness of training and skills development. We incorporate assessments into all our training courses and ask for feedback post-session to help us understand what each user learned, but we also depend on a system of certifications that are backed up by exams.

A Zabbix certification is our guarantee that a certificate holder has mastered the theoretical and practical skills covered during a course. Participants must score 80% or higher to pass any exam, which is why they stand as concrete proof that a certificate holder has the required knowledge to understand the concepts presented in a training session and implement them in real Zabbix environments.

Conclusion

Zabbix has a wide variety of users, so we need to offer a wide variety of courses to meet their needs. Our training programs are intended for IT administrators, auditors, system integrators, and anyone else who deals with IT infrastructure monitoring.

We’re proud of the fact that even veteran administrators with several years of Zabbix experience come away from our trainings armed with inside knowledge of new features and best practices.
To find out more about our comprehensive suite of trainings and find the one that’s right for you or your organization, visit zabbix.com/training.


The post Training and Skills Development: The Zabbix Advantage appeared first on Zabbix Blog.

Online Retail Hack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/11/online-retail-hack.html

Selling miniature replicas to unsuspecting shoppers:

Online marketplaces sell tiny pink cowboy hats. They also sell miniature pencil sharpeners, palm-size kitchen utensils, scaled-down books and camping chairs so small they evoke the Stonehenge scene in “This Is Spinal Tap.” Many of the minuscule objects aren’t clearly advertised.

[…]

But there is no doubt some online sellers deliberately trick customers into buying smaller and often cheaper-to-produce items, Witcher said. Common tactics include displaying products against a white background rather than in room sets or on models, or photographing items with a perspective that makes them appear bigger than they really are. Dimensions can be hidden deep in the product description, or not included at all.

In those instances, the duped consumer “may say, well, it’s only $1, $2, maybe $3­—what’s the harm?” Witcher said. When the item arrives the shopper may be confused, amused or frustrated, but unlikely to complain or demand a refund.

“When you aggregate that to these companies who are selling hundreds of thousands, maybe millions of these items over time, that adds up to a nice chunk of change,” Witcher said. “It’s finding a loophole in how society works and making money off of it.”

Defrauding a lot of people out of a small amount each can be a very successful way of making money.

След изборите – по-високи данък сгради, по-високи разходи при покупка на имот и теглене на нов заем от 2.3 млр. EUR

Post Syndicated from VassilKendov original https://kendov.com/%D1%81%D0%BB%D0%B5%D0%B4-%D0%B8%D0%B7%D0%B1%D0%BE%D1%80%D0%B8%D1%82%D0%B5-%D0%BF%D0%BE-%D0%B2%D0%B8%D1%81%D0%BE%D0%BA%D0%B8-%D0%B4%D0%B0%D0%BD%D1%8A%D0%BA-%D1%81%D0%B3%D1%80%D0%B0%D0%B4/

Ден след изборите, България изтегли заем за 2.3 млр. евро от международните пазари. Паралелно с това се обсъжда нова методика за определяне на данъчните оценки на имотите, от които зависят пряко резмера на местния данък, така смет и нотариалните такси при покупка на имот.
Целият пакет данъчни закони вече е на сайта на парламента, като очакванията са депутатите да започнат да ги гласуват до края на седмицата. А новото там е, че се предлага заведенията да запазят ДДС привилегията си още една година.

С промените в ЗМДТ (закон за местните данъци и такси) се предлага размерът на данък сгради да може да се диференцира от общините по населени места, по зони в тях или по вид на имотите. Общините да могат също да променят данъчните оценки на жилищата на всеки ДВЕ ГОДИНИ в зависимост от състоянието на пазара на имоти.

И двете събития имат един и същ произход – стремежът да се запази дефицита в бюджета в рамките на 3%, което е ключово важно за приемането ни в еврозоната.

Това е добре, но обещанията на управляващите и съответно държавните разходи се увеличават всяка година, което налага финансиране на тези разходи. То става по 2 начина – чрез увеличаване на данъците от една страна и теглене на заем от друга, за да се финансира този планиран дефицит от 3%.
Реално погледнато, новия външен дълг е планиран в този бюджет. Тази година България пое външен дълг от 7.5 млрд лева, с част от който рефинансира съществуващи кредити, а с част от него финансира дефицита.

Моите наблюдения от години са, че българската икономика има нужда от около 4.5 млрд лева заем всяка година, за да финансира неефективността си.
В тази връзка в тримесечния доклад на БНБ бяха обявени доста обнадеждаващи данни и статистика, които с този нов външен дълг, вече не са толкова обнадждаващи.

„Към юни 2023 г. брутният външен дълг на България възлезе на 44.1 млрд. евро (49.3%от БВП), което представлява понижение с 375.6 млн. евро спрямо декември 2022г. (52.5% от БВП). Повишение на външния дълг се наблюдаваше единствено при сектор „държавно управление“ и банковия сектор.”

Така изглеждаха нещата до понеделник 06.11.2023

По спомен преди окло 3 години, държавния дълг беше едва около 35% от БВП и това беше гордостта на Бойко Борисов. С новия дълг, отново минаваме над 50% от БВП. А ако вземем предвид прогнозите на специалистите от Мин. на Финансите и моите лични прогнози, дългът ни трайно ще остане над 50% от БВП.

В икономическата теория е прието, че дълг се поема за развитие и инвестиции, но в нашия случай според мен не е така. С тези заеми се финансират обещания и нови „правителствени програми”, често пъти в социалната сфера.

 Нека се върнем към увеличаването на данъчната оценка на имотите, понеже тя има по-директна връзка с „джобовете” на хората.

Поетият нов дълг също също, но неовото въздействие по-трудно се осмисля от средностатистическия човек. Само да вметна, че увеличаването на дълга е свързано с увеличаването на данъците. И двете имат за цел да финансират бюджетния дефицит, който в нашия случай се използва за реализиране на политически обещания, а не инвестиции. Просто вдигането на данъка по-лесно го осмисляме и усещаме.
ето каква казва Асен Василев по случая

“Нека да видим какво ще се случи с данъчните закони, които ще финализират приходната част. На база на това ще бъдат довършени всички останали разчети”, заяви Асен Василев.

Увеличаването на данъчната оценака на имотите е пряко свързана със следните разходи, които правим:
– Данък сгради, който плащаме ежегодно
– Такса смет, която плащаме ежегодно
– Местен данък, който плащаме при покупка на имот (еднократен)
– Нотариални такси при покупка на имот (еднократни)

В новите промени се предвижда общините да използват индексите на НСИ за цените на имотите по региони за определяне на пазарната цена на имота и това да става веднъж на 2 години.
Предвидено е също така всяка община да може да прилага диференцирани данъци за имоти на по-добри локации или по-големи и луксозни имоти.
Откъдето и да го погледнем, годишните разходи за притежанието на имот ще се увеличат. За покупката също. Сами можете да прецените как това ще повлияе пазара на имоти, който и без това отчита спад от 15% за последното тримесечие. Новите разрешителни за строеж също отчитат спад на годишна база.

Безплатен съвет за челите до края – ако ще продавате имот, правете го до Нова година. После ще е различно!

За коментари и обсъждания на тема кредити и финанси, можете да се абонирате за Telegram канала Kendov.com

Васил Кендов – финансист

За  срещa с мен при нужда от кредит или нередовен кредит,
моля използвайте посочената форма.

[contact-form-7]


The post След изборите – по-високи данък сгради, по-високи разходи при покупка на имот и теглене на нов заем от 2.3 млр. EUR appeared first on Kendov.com.

The Next Step in Personalization: Dynamic Sizzles

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/the-next-step-in-personalization-dynamic-sizzles-4dc4ce2011ef

Authors:Bruce Wobbe, Leticia Kwok

Additional Credits:Sanford Holsapple, Eugene Lok, Jeremy Kelly

Introduction

At Netflix, we strive to give our members an excellent personalized experience, helping them make the most successful and satisfying selections from our thousands of titles. We already personalize artwork and trailers, but we hadn’t yet personalized sizzle reels — until now.

A sizzle reel is a montage of video clips from different titles strung together into a seamless A/V asset that gets members excited about upcoming launches (for example, our Emmys nominations or holiday collections). Now Netflix can create a personalized sizzle reel dynamically in real time and on demand. The order of the clips and included titles are personalized per member, giving each a unique and effective experience. These new personalized reels are called Dynamic Sizzles.

In this post, we will dive into the exciting details of how we create Dynamic Sizzles with minimal human intervention, including the challenges we faced and the solutions we developed.

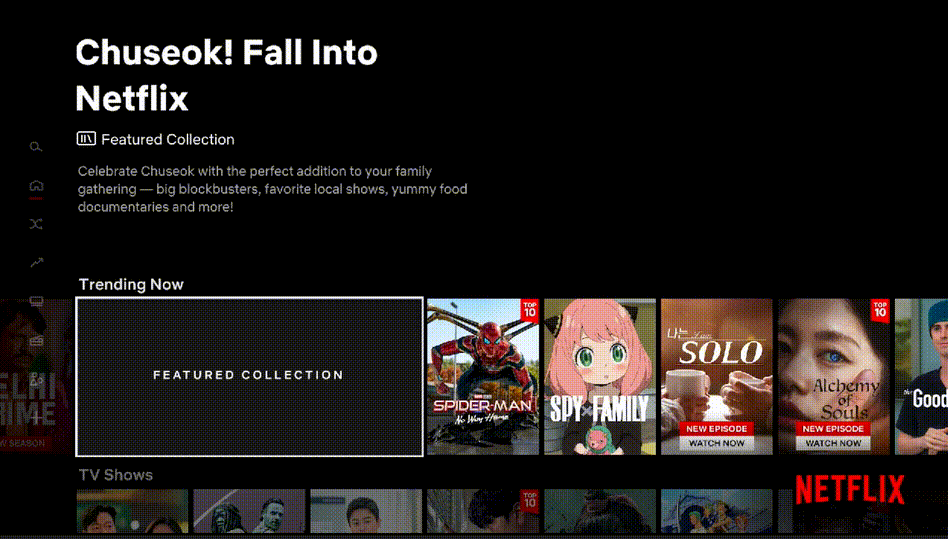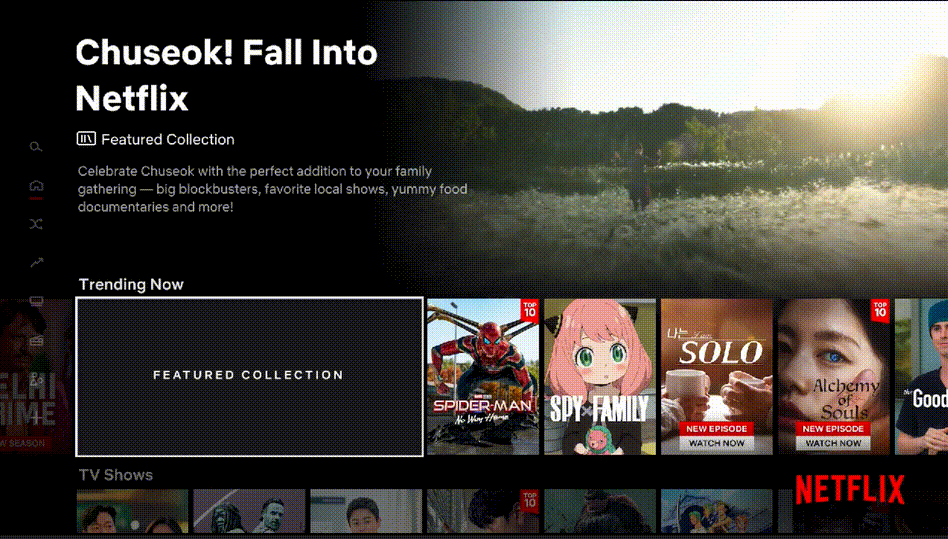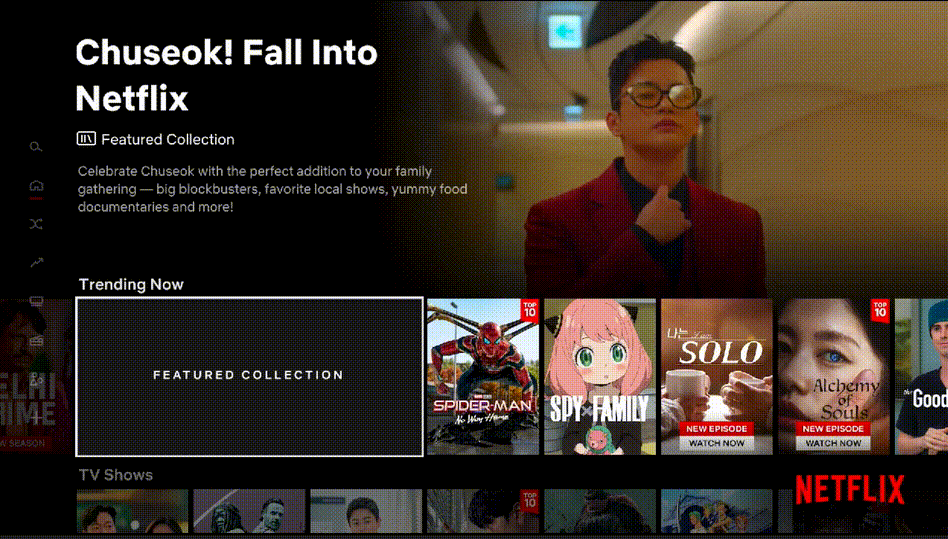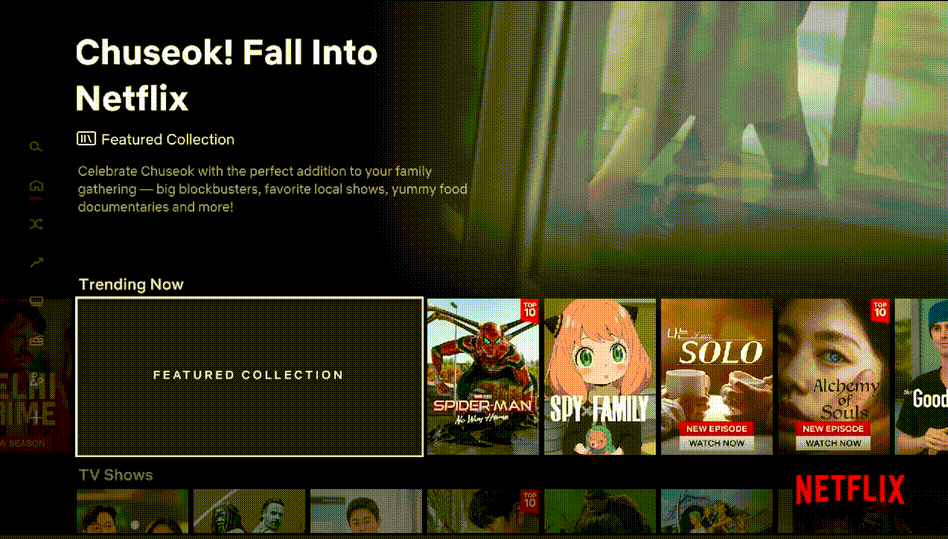
An example of a Dynamic Sizzle created for Chuseok, the Korean mid-autumn harvest festival collection.

Overview

In the past, each sizzle reel was created manually. The time and cost of doing this prevents scaling and misses the invaluable benefit of personalization, which is a bedrock principle at Netflix. We wanted to figure out how to efficiently scale sizzle reel production, while also incorporating personalization — all in an effort to yield greater engagement and enjoyment for our members.

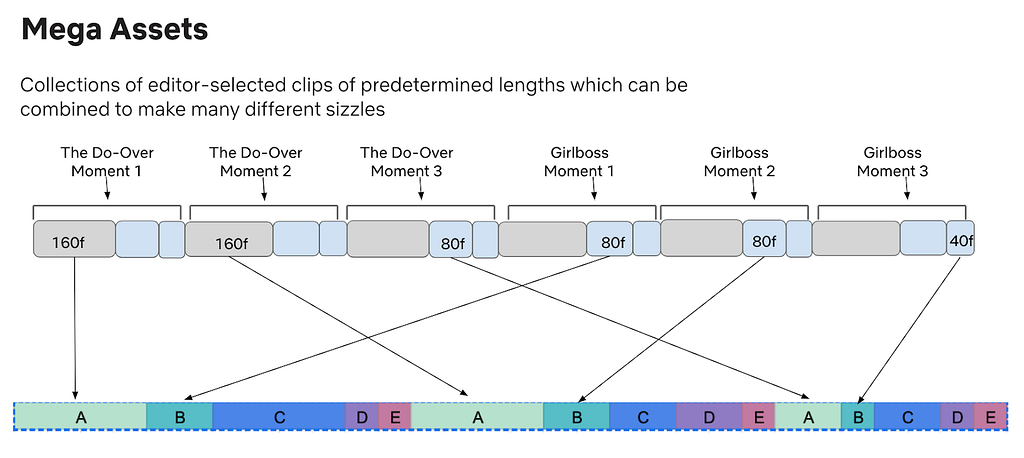
Enter the creation of Dynamic Sizzles. We developed a systems-based approach that uses our interactive and creative technology to programmatically stitch together multiple video clips alongside a synced audio track. The process involves compiling personalized multi-title/multi-talent promotional A/V assets on the fly into a Mega Asset. A Mega Asset is a large A/V asset made up of video clips from various titles, acting as a library from which the Dynamic Sizzle pulls media. These clips are then used to construct a personalized Dynamic Sizzle according to a predefined cadence.

With Dynamic Sizzles, we can utilize more focused creative work from editors and generate a multitude of personalized sizzle reels efficiently and effectively — up to 70% in terms of time and cost savings than a manually created one. This gives us the ability to create thousands, if not millions, of combinations of video clips and assets that result in optimized and personalized sizzle reel experiences for Netflix members.

Creating the Mega Asset

Where To Begin

Our first challenge was figuring out how to create the Mega Asset, as each video clip needs to be precise in its selection and positioning. A Mega Asset can contain any number of clips, and millions of unique Dynamic Sizzles can be produced from a single Mega Asset.

We accomplished this by using human editors to select the clips — ensuring that they are well-defined from both a creative and technical standpoint — then laying them out in a specific known order in a timeline. We also need each clip marked with an index to its location — an extremely tedious and time consuming process for an editor. To solve this, we created an Adobe Premiere plug-in to automate the process. Further verifications can also be done programmatically via ingestion of the timecode data, as we can validate the structure of the Mega Asset by looking at the timecodes.

An example of a title’s video clips layout.

The above layout shows how a single title’s clips are ordered in a Mega Asset and in 3 different lengths: 160, 80 and 40 frame rates. Each clip should be unique per title; however, when using multiple titles, they may share the same frame rate. This gives us more variety to choose from while maintaining a structured order in the layout.

Cadence

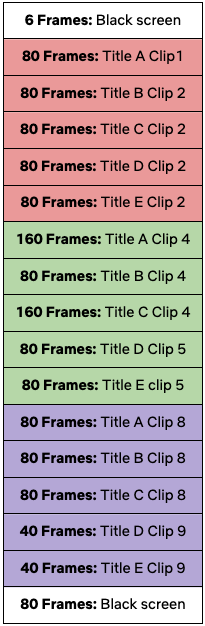
The cadence is a predetermined collection of clip lengths that indicates when, where, and for how long a title shows within a Dynamic Sizzle. The cadence ensures that when a Dynamic Sizzle is played, it will show a balanced view of any titles chosen, while still giving more time to a member’s higher ranked titles. Cadence is something we can personalize or randomize, and will continue to evolve as needed.

Sample Cadence

In the above sample cadence, Title A refers to the highest ranked title in a member’s personalized sort, Title B the second highest, and so on. The cadence is made up of 3 distinct segments with 5 chosen titles (A-E) played in sequence using various clip lengths. Each clip in the cadence refers to a different clip in the Mega Asset. For example, the 80 frame clip for title A in the first (red) segment is different from the 80 frame clip for title A in the third (purple) segment.

Composing the Dynamic Sizzle

Personalization

When a request comes in for a sizzle reel, our system determines what titles are in the Mega Asset and based on the request, a personalized list of titles is created and sorted. The top titles for a member are then used to construct the Dynamic Sizzle by leveraging the clips in the Mega Asset. Higher ranked titles get more weight in placement and allotted time.

Finding Timecodes

For the Dynamic Sizzle process, we have to quickly and dynamically determine the timecodes for each clip in the Mega Asset and make sure they are easily accessed at runtime. We accomplish this by utilizing Netflix’s Hollow technology. Hollow allows us to store timecodes for quick searches and use timecodes as a map — a key can be used to find the timecodes needed as defined by the cadence. The key can be as simple as titleId-clip-1.

Building The Reel

The ordering of the clips are set by the predefined cadence, which dictates the final layout and helps easily build the Dynamic Sizzle. For example, if the system knows to use title 17 within the Mega Asset, we can easily calculate the time offset for all the clips because of the known ordering of the titles and clips within the Mega Asset. This all comes together in the following way:

The result is a series of timecodes indicating the start and stop times for each clip. These codes appear in the order they should be played and the player uses them to construct a seamless video experience as seen in the examples below:

The Beautiful Game Sizzle
The Beautiful Game Dynamic Sizzle

With Dynamic Sizzles, each member experiences a personalized sizzle reel.

Example of what 2 different profiles might see for the same sizzle

Playing the Dynamic Sizzle

Delivering To The Player

The player leverages the Mega Asset by using timecodes to know where to start and stop each clip, and then seamlessly plays each one right after the other. This required a change in the API that devices normally use to get trailers. The API change was twofold. First, on the request we need the device to indicate that it can support Dynamic Sizzles. Second, on the response the timecode list needs to be sent. (Changing the API and rolling it out took time, so this all had to be implemented before Dynamic Sizzles could actually be used, tested, and productized.)

Challenges With The Player

There were two main challenges with the player. First, in order to support features like background music across multiple unique video segments, we needed to support asymmetrical segment streaming from discontiguous locations in the Mega Asset. This involved modifying existing schemas and adding corresponding support to the player to allow for the stitching of the video and audio together separately while still keeping the timecodes in sync. Second, we needed to optimize our streaming algorithms to account for these much shorter segments, as some of our previous assumptions were incorrect when dealing with dozens of discontiguous tiny segments in the asset.

Building Great Things Together

We are just getting started on this journey to build truly great experiences. While the challenges may seem endless, the work is incredibly fulfilling. The core to bringing these great engineering solutions to life is the direct collaboration we have with our colleagues and innovating together to solve these challenges.

If you are interested in working on great technology like Dynamic Sizzles, we’d love to talk to you! We are hiring: jobs.netflix.com


The Next Step in Personalization: Dynamic Sizzles was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Let’s Architect! Tools for developers

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-tools-for-developers/

In the software development process, adopting developer tools makes it easier for developers to write code, build applications, and test more efficiently. As a developer, you can use various AWS developer tools for code editing, code quality, code completion, and so on. These tools include Amazon CodeGuru for code analysis, and Amazon CodeWhisper for getting coding recommendations powered by machine learning algorithms.

In this edition of Let’s Architect!, we’ll show you some tools that every developer should consider including in their toolkit.

10 ways to build applications faster with Amazon CodeWhisperer

This blog post shares several prompts to enhance your programming experience with Amazon CodeWhisperer.

Why is this important to developers? By default, CodeWhisperer gives you code recommendations in real time — this example shows you how to make the best use of these recommendations. You’ll see the different dimensions of writing a simple application, but most importantly, you’ll learn how to resolve problems you could face in development workflows. Even if you’re just a beginner, you’ll be able to use this example to leverage AI to increase productivity.

Take me to this blog post!

Ten best practices to build applications faster with CodeWhisperer

Ten best practices to build applications faster with CodeWhisperer

Automate code reviews with Amazon CodeGuru Reviewer

Code quality is important in software development. It’s essential for resilient, cost-effective, and enduring software systems. It helps guarantee performance efficiency and satisfy functional requirements, but also guarantee long-term maintainability.

In this blog post, the authors talk about the advantages offered by CodeGuru automated code reviews, which allow you to proactively identify and address potential issues before they find their way into the main branches of your repository. CodeGuru not only streamlines your development pipeline, but also fortifies the integrity of your codebase, ensuring that only the highest quality code makes its way into your production environment.

Take me to this blog post!

Adding cdk-watch in the stack

Adding cdk-watch in the stack

Powertools for AWS Lambda (Python)

AWS provides various tools for developers. You can access the complete list here. One in particular—Lambda Power Tools—is designed to implement serverless best practices and elevate developer velocity. Powertools for AWS Lambda (Python) is a library of observability best practices and solutions to common problems like implementing idempotency or handling batch errors. It supports different languages, such as Python, Java, Typescript, and .Net and lets you choose choose your favorite(s). There is also a roadmap available, so you can see upcoming features.

Check out this tool!

Homepage of Powertools for AWS Lambda (Python)

Homepage of Powertools for AWS Lambda (Python)

Increasing development speed with CDK Watch

Developers test their code in an AWS account to see if their changes are working successfully, especially when developing new infrastructure workloads programmatically or provisioning new services. AWS Cloud Development Kit (AWS CDK) CLI has a flag called hotswap that helps to speed up your deployments. It does this by swapping specific resources, without going through the whole AWS CloudFormation process.

Not all changes can be hotswapped, though. When hotswapping isn’t possible, cdk-watch will go back to using a full CloudFormation deployment. NOTE: This command deliberately introduces drift in CloudFormation to speed up deployments. For this reason, only use it for development purposes. Never use hotswap for your production deployments!

Take me to this blog post!

CodeGuru implemented in this end-to-end CICD pipeline

CodeGuru implemented in this end-to-end CICD pipeline

See you next time!

Thanks for reading! This is the last post for 2023. We hope you enjoyed our work this year and we look forward to seeing you in 2024.

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page. Thank you for being a part of our community, and we look forward to bringing you more insightful content in the future. Happy re:Invent, everybody!

[$] Reducing patch postings to linux-kernel

Post Syndicated from jake original https://lwn.net/Articles/950567/

The linux-kernel mailing list famously gets an enormous amount of email on a
daily basis; the volume is so high that various email providers try to
rate-limit it, which can lead to huge backlogs on the sending
side and, of course, delayed mail. Part of the reason there is so much
traffic is that nearly every patch gets copied to the mailing list, even
when it may be unnecessary to do so. A proposed change
would start shunting some of that patch email aside and, as might be
guessed, has both supporters and detractors, but the discussion does
highlight some of the
different ways the mailing list is used by kernel developers.

Real-time streaming data top picks you cannot miss at AWS re:Invent 2023

Post Syndicated from Anna Montalat original https://aws.amazon.com/blogs/big-data/real-time-streaming-data-top-picks-you-cannot-miss-at-aws-reinvent-2023/

Save the date: AWS re:Invent 2023 is happening from November 27 to December 1 in Las Vegas, and you cannot miss it. re:Invent is a learning conference organized by AWS for the global cloud computing community. It’s a great opportunity to come together with cloud enthusiasts from around the world to hear about the latest cloud industry innovations, meet with AWS experts, have fun, and build connections.

Join us as we delve into the world of real-time streaming data at re:Invent 2023 and discover how you can use real-time streaming data to build new use cases, optimize existing projects and processes, and reimagine what’s possible. In today’s data-driven landscape, the quality of data is the foundation upon which the success of organizations and innovations stands. High-quality data is not just about accuracy; it’s also about timeliness. To derive meaningful insights and ensure the optimal performance of machine learning (ML) and generative AI models, data needs to be ingested and processed in real time. Real-time data empowers these models to adapt and respond instantaneously to changing scenarios, making them not just smarter but also more practical. With real-time streaming data, organizations can reimagine what’s possible. From enabling predictive maintenance in manufacturing to delivering hyper-personalized content in the media and entertainment industry, and from real-time fraud detection in finance to precision agriculture in farming, the potential applications are vast.

This post will help you plan your re:Invent experience by highlighting the essential sessions on real-time streaming data and beyond that you shouldn’t miss. To attend these sessions, be sure to register for re:Invent and access the session catalog. Register now!

Keynotes and Innovation Talk sessions you cannot miss!

Don’t miss your chance to hear from some of the leading voices in AWS. Here are some of our favorite keynotes and Innovation Talk sessions.

Adam Selipsky, Chief Executive Officer of Amazon Web Services – Keynote

Tuesday, November 28 | 8:30 AM – 10:30 AM PST | The Venetian

Join Adam Selipsky, CEO of Amazon Web Services, as he shares his perspective on cloud transformation. He highlights innovations in data, infrastructure, and artificial intelligence and machine learning that are helping AWS customers achieve their goals faster, mine untapped potential, and create a better future.

Reserve your seat now!

Swami Sivasubramanian, Vice President of AWS Data and AI– Keynote

Wednesday, November 29 | 8:30 AM – 10:30 AM PST | The Venetian

Join Swami Sivasubramanian, Vice President of Data and AI at AWS, to discover how you can use your company’s data to build differentiated generative AI applications and accelerate productivity for employees across your organization. Also hear from customer speakers with real-world examples of how they’ve used their data to support their generative AI use cases and create new experiences for their customers.

Reserve your seat now!

Putting your data to work with generative AI – Innovation Talk

Thursday, November 30 | 12:30 – 1:30 PM PST | The Venetian

Join Mai-Lan Tomsen Bukovec, Vice President, Technology at AWS to learn how you can turn your data lake into a business advantage with generative AI. Explore strategies for putting your proprietary datasets to work when building unique, differentiated generative AI solutions. Learn how to utilize your datasets using Amazon SageMaker and Amazon Bedrock and popular frameworks like PyTorch with AWS compute, storage, and analytics. Hear best practices for using unstructured (video, image, PDF), semi-structured (Parquet), and table-formatted (Iceberg) data for training, fine-tuning, checkpointing, and prompt engineering. Also hear different architectural patterns that customers use today to harness their business data for customized generative AI solutions.

Reserve your seat now!

Data drives transformation: Data foundations with AWS analytics – Innovation Talk

Thursday, November 30 | 2:00 – 3:00 PM PST | The Venetian

Join G2 Krishnamoorthy, Vice President of AWS Analytics, to discuss strategies for embedding analytics into your applications and ideas for building a data foundation that supports your business initiatives. With new capabilities for self-service and simpler builder experiences, you can democratize data access for line-of-business users, analysts, scientists, and engineers. Hear inspiring stories from adidas, GlobalFoundries, and the University of California, Irvine.

Reserve your seat now!

Breakout sessions

Deepen your learning with re:Invent breakout sessions. re:Invent breakout sessions are lecture-style and 1 hour long. These sessions take place across the re:Invent campus and cover all topics at all levels. The following are some of our favorites:

  • Accelerate innovation with real-time data: Join Mindy Ferguson, Vice President of Streaming and Messaging at AWS, and Arvinth Ravi, General Manager of Amazon Kinesis Data Streams, in this session that highlights the importance of implementing ubiquitous real-time data strategies to gain a competitive edge. Discover the latest launches in AWS streaming data services, gain insights into real-world applications, and explore how you can use them to solve a variety of use cases to make quick, real-time decisions to optimize costs, increase customer engagement, and drive growth. Reserve your seat now!
  • How Rivian builds real-time analytics from electric vehicles: Learn how Rivian’s vehicle data platform team uses Amazon MSK and other AWS analytics services to build a secure, scalable, cost-effective, and extensible data platform that powers different teams across the organization. Reserve your seat now!
  • Serverless data streaming: Amazon Kinesis Data Streams and AWS Lambda: Explore the intricacies of creating scalable, production-ready data streaming architectures using Amazon Kinesis Data Streams and AWS Lambda. Delve into tips and best practices essential to navigating the challenges and pitfalls inherent to distributed systems that arise along the way, and observe how AWS services work and interact. Reserve your seat now!
  • Break down data silos using real-time synchronization with Flink CDC: Learn how, by using Flink CDC on AWS, you can simplify real-time synchronization and ingestion across transactional databases and finally break down data silos. Reserve your seat now!
  • Scaling serverless data processing with Amazon Kinesis and Apache Kafka: Explore how to build scalable data processing applications using AWS Lambda. Learn practical insights into integrating Lambda with Amazon Kinesis and Apache Kafka using their event-driven models for real-time data streaming and processing. Design serverless data processing pipelines and extract valuable insights from real-time data streams. Reserve your seat now!

Chalk talks

Chalk talks are a highly interactive content format with a small audience. Each begins with a short lecture delivered by an AWS expert followed by a Q&A session with the audience.

  • Stream data and build transactional lakes with AWS Glue streaming: Learn how to create a low-code streaming pipeline with AWS Glue and Amazon Kinesis to load, clean, and transform sales data, and make it available for machine learning. Reserve your seat now!
  • Migrating self-managed Apache Flink to fully managed on AWS: Review key details to keep in mind when migrating self-managed Apache Flink applications to Amazon Managed Service for Apache Flink. Explore how using cloud-based services with the right patterns can reduce operational overhead. Hear about best practices that can help with migration while still maintaining costs, scale, and performance. Reserve your seat now!
  • How to migrate your Apache Kafka workloads to Amazon MSK: Amazon Managed Streaming for Apache Kafka (Amazon MSK) is an AWS streaming data service that manages Apache Kafka infrastructure and operations. Learn the benefits of migrating to Amazon MSK and how to lift and shift existing clusters using MirrorMaker 2.0 (MM2). Take a deep dive into the MM2 and Kafka Connect architecture, and explore the common bottlenecks and challenges of high-throughput data streams. Reserve your seat now!
  • Accelerating value from data: Migrate from batch to stream processing: Explore the competitive advantages of transitioning from traditional batch processing to stream processing. Look at key concepts and architectural patterns of streaming to address potential challenges and hiccups along this migration journey. Through an example use case, gain insights into how to successfully transition from batch to real-time data processing using AWS streaming data services. Reserve your seat now!
  • Fast-track streaming ETL with AWS streaming data services: Learn how to build streaming data pipelines across data lakes and data warehouses. Learn best practices for performance, scale, and cost control in Amazon Kinesis Data Streams, Amazon MSK, Amazon Redshift streaming ingestion, and AWS Glue streaming. Reserve your seat now!
  • Advanced real-time analytics and ML in your data warehouse: Learn how enterprise customers are rearchitecting their data environments to lean more heavily on streaming analytics to process throughput of millions of records per second. We will show you how to implement an ELT approach that uses Amazon Redshift’s native integration with streaming data services and Amazon Redshift ML to build near-real-time ML predictions in SQL for better decision-making. Reserve your seat now!
  • Building better with Apache Kafka and Amazon EventBridge: Explore the convergence of event-driven architectures and real-time event streaming to meet modern business requirements. Learn about Amazon EventBridge and Apache Kafka and gain insights into their roles for facilitating real-time decision-making, increased business velocity, and operational autonomy. Reserve your seat now!
  • Speed up data predictions with real-time inference at scale: It is crucial to analyze, learn, and make predictions from your data in a timely manner because the value of data diminishes over time. Dive into event-driven architecture and see how you can use machine learning inference with streaming data to detect patterns and anomalies to realize a faster path to decisions from your data. Reserve your seat now!

Code Talk

Code Talks are 60-minute sessions that focus on the actual code involved in building a solution. You’ll learn the “why” behind the solution and see it come to life—complete with the inevitable errors. Your questions are welcome and encouraged.

  • Build a Flink application on Amazon Managed Service for Apache Flink: Join this code talk to develop and host a streaming and production-ready Apache Flink application on Amazon Managed Service for Apache Flink using the DataStream and Table API programming models. Reserve your seat now!

Workshops

Workshops are 2-hour hands-on sessions where you work in teams to solve problems using AWS services. Workshops organize attendees into small groups and provide scenarios to encourage interaction, giving you the opportunity to learn from and teach each other. Don’t forget to bring your laptop!

  • Event detection with MSK and Amazon Managed Service for Apache Flink: Take on the role of a technology manager for a Las Vegas casino. Learn how to create a stream-processing application that identifies historically “high roller” casino guests entering the casino and that sends you an email when they sit down at a gambling table. Reserve your seat now!

Bootcamp

Bolster your confidence with AWS services and solutions in these eight-hour, deep-dive sessions. Learn by doing with expert guidance, immersive exercises, and self-paced labs.

The below is one you cannot miss:

  • Building streaming data analytics solutions on AWS: Learn to design and implement streaming data analytics solutions using AWS services with an expert AWS instructor. This 8-hour, deep-dive bootcamp is designed for data engineers, solutions architects, and developers who want to build and manage streaming data analytics pipelines. This bootcamp covers how to scale streaming applications using Amazon Kinesis; how to optimize data storage; how to select and deploy appropriate options to ingest, transform, store, and analyze data; and more. You can practice new skills in a real AWS environment with hands-on labs that cover data analytics solutions. Reserve your seat now!

Still time for FUN!

All work and no play … not at re:Invent! Sure, we’ll work hard and learn a lot, but we also plan to have a great time while we’re together. AWS Builder Labs will give you the opportunity to test your skills in sandbox settings while working alongside some of the leading minds from AWS!

Join the PeerTalk platform to easily find, connect, and network with others at re:Invent. Opt in to discover attendees who share similar interests—PeerTalk recommends connections for you. Browse recommendations, message people, and arrange meetups through the platform, then sit down for a face-to-face conversation in one of the four PeerTalk lounges located throughout the re:Invent campus.

Stop by the Analytics kiosk in the re:Invent expo hall. Connect with experts to dive deeper into AWS streaming data services such as Amazon Kinesis Data Streams, Amazon Kinesis Data Firehose, Amazon Managed Service for Apache Flink, and Amazon Managed Streaming For Apache Kafka (Amazon MSK). Also, win prizes, show off your Analytics superhero, and learn all about the latest innovations from our AWS Analytics services.

Register today

It’s going to be an amazing event, and we can’t wait to see you at re:Invent 2023! Register now to secure your spot!


About the author

Anna Montalat is a Senior Product Marketing Manager for AWS streaming data services which includes Amazon Managed Streaming for Apache Kafka (MSK), Kinesis Data Streams, Kinesis Video Streams, Kinesis Data Firehose, and Kinesis Data Analytics. She is passionate about bringing new and emerging technologies to market, working closely with service teams and enterprise customers. Outside of work, Anna skis through winter time and sails through summer.

The collective thoughts of the interwebz