Tag Archives: data

Data Mesh at Grab (Part III): Operationalizing data reliability with automated DPIs

Post Syndicated from Grab Tech original https://engineering.grab.com/data-mesh-at-grab-part-three

Introduction

In the first two parts of this series, we described how Grab approaches data mesh through the Signals Marketplace: a way for teams to publish, discover, and reuse trusted data products across domains. Part II introduced the foundational tools behind certification: Hubble for metadata and ownership, Genchi for data quality observability, and the Data Contract Registry for explicit producer-consumer guarantees.

Certification is the starting point for a trusted data marketplace. It gives downstream consumers confidence in an asset’s ownership, documentation, lineage, and quality controls. Certification does not eliminate runtime failure. A certified table can still arrive late. A certified metric can still be affected by a broken dependency. A certified Kafka stream can still violate a freshness expectation.

Keeping certified data products reliable in production requires more than defining standards upfront. Teams need a consistent way to detect failures, diagnose the root cause, fix the issue, and verify recovery. That is where Data Production Issues (DPIs) come in. At Grab, DPIs turn data quality signals into an operational workflow.

The DPI lifecycle

A good DPI should be clear enough to act on, and it should close automatically when the underlying condition recovers. From the beginning, we designed the DPI lifecycle to be automated, with minimal human-in-the-loop.

The lifecycle starts when Kinabalu, Grab’s incident orchestrator, observes that a data asset may no longer satisfy its contract. The contract captures the reliability expectations that matter for the asset, along with the health checks, exposed through Test Health application programming interfaces (APIs), that evaluate those expectations.

The orchestrator stays decoupled from platform internals. It does not need to know how each platform computes freshness, completeness, or other quality dimensions. It only needs to ask whether the relevant contract tests are healthy. If one or more contract tests are unhealthy, the contract is considered breached, and the DPI lifecycle begins.
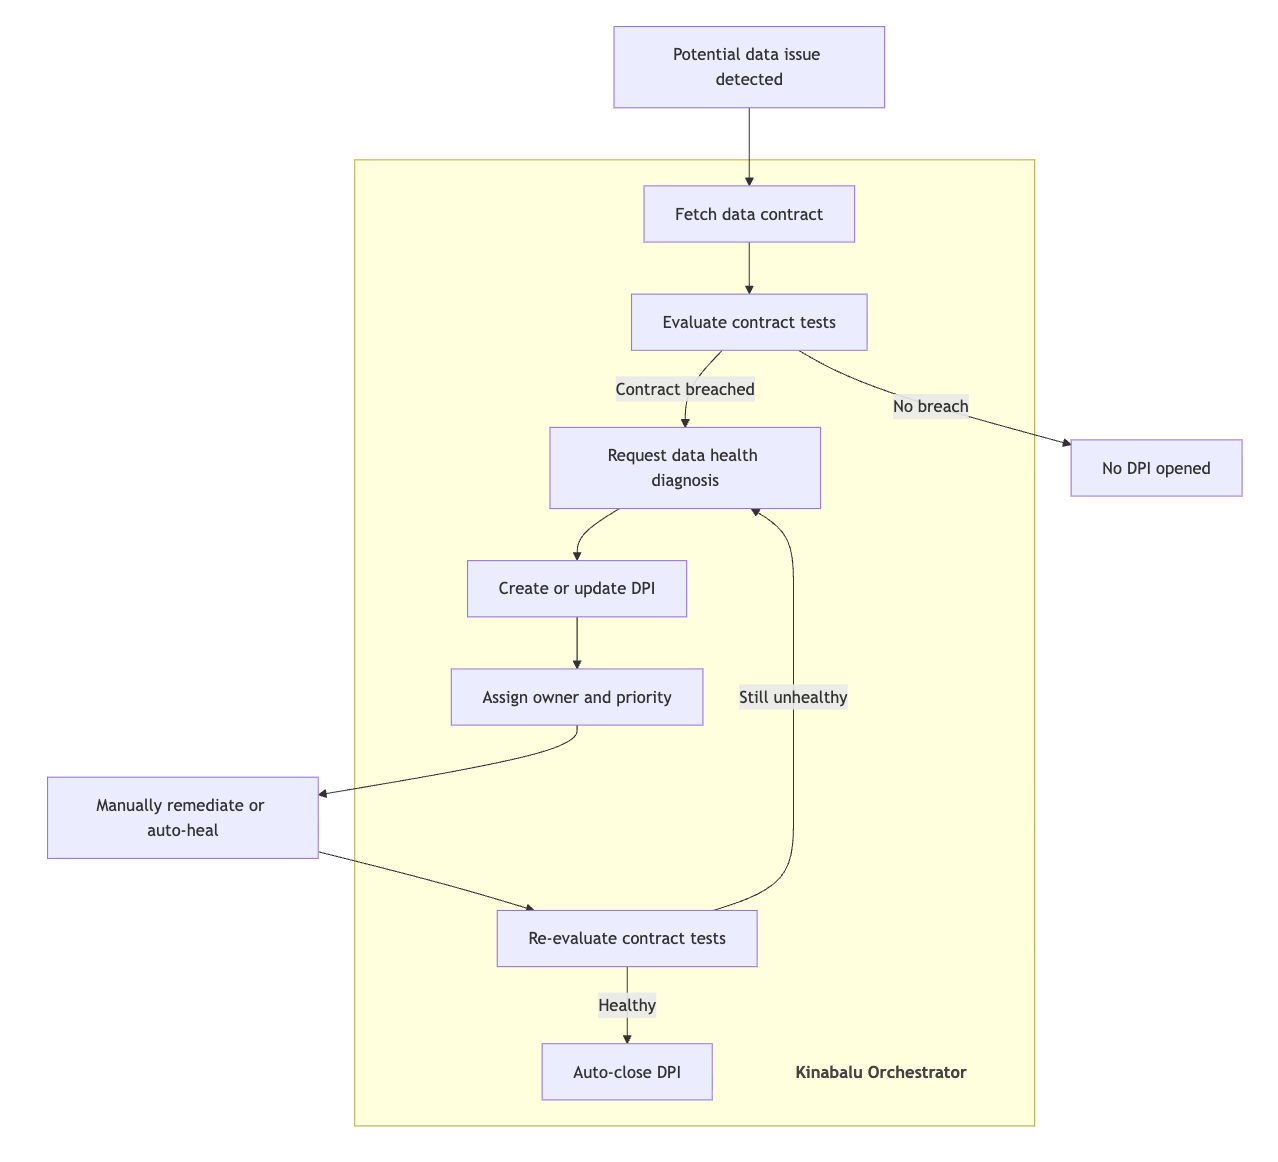
Diagram of the automated Data Production Issue workflow from contract-test evaluation through triage, diagnosis, resolution, and close.
Figure 1. Automated DPI workflow.

Triaging DPIs: From alerts to confirmed contract breaches

Data platforms emit many alerts. An Airflow schedule may be delayed, a data quality test may fail, or a pipeline job may exit unexpectedly. These alerts are useful, but they are not automatically DPIs. Triage decides whether an alert represents a real contract breach for a data asset.

As introduced in Part II, a data contract is an explicit, versioned agreement between a data producer and its consumers. It outlines the data’s schema, freshness, completeness, and other semantic guarantees. These guarantees are codified and enforced through data quality tests in Genchi.

When the incident orchestrator evaluates contract tests, it distinguishes an individual test run result from the overall health of a test. A test run can pass or fail at a point in time, but the test itself may only be considered healthy after the underlying issue has been fully resolved. For example, consider a completeness test that checks whether the T-1 daily partition is complete. If the test failed two days ago but passed yesterday and today, the test may still be considered unhealthy until the partition from two days ago has been backfilled and verified as complete.

The orchestrator also deduplicates around the active unhealthy condition. If an asset already has an open DPI for the same breach, new signals update the existing DPI with additional context rather than creating parallel issues. DPIs that share the same underlying root cause can also be grouped. This keeps responders focused on solving the underlying issue rather than chasing a stream of repetitive alerts.

During triage, the workflow also gathers context for the DPI: affected asset, breached contract, unhealthy tests, data interval, and upstream and downstream dependencies. Not every alert becomes a DPI. Triage protects the operational workflow from noise by promoting only meaningful contract breaches into production issues.

Diagnosing DPIs: Assigning owners with root cause analysis (RCA)

Once a DPI is created, the system must answer why the data is unhealthy, who should fix it, and how.

Not every data issue should be assigned to the data asset owner. A data product may be unhealthy because of a platform incident, a failed producing job, or a delayed upstream dependency. Assigning every issue to the asset owner creates unnecessary handoffs and slows down resolution.

This is where the Data Health API matters. It answers the question: “What kind of failure made this asset unhealthy?” The Data Health API keeps the error taxonomy small:

  • UPSTREAM_ERROR: the asset is unhealthy because an upstream dependency is late, failed, or unavailable.
  • PLATFORM_ERROR: the asset is unhealthy because the underlying platform or infrastructure is impaired.
  • JOB_ERROR: the asset is unhealthy because the producing job or pipeline failed.
  • DATA_ERROR: the asset is unhealthy because the produced data violates quality expectations.

The taxonomy is not meant to replace platform-specific diagnostics. The high-level Data Health API gives the orchestrator just enough structure to assign DPIs and manage their lifecycle consistently. An ingestion platform, streaming platform, metrics platform, or machine learning (ML) platform can still maintain detailed internal error catalogs, logs, retry states, and debugging tools. Platforms remain free to evolve their internals, while the incident orchestrator consumes a stable API contract, so the DPI workflow can interoperate across heterogeneous systems.

A simplified Data Health API response might look like this:

Disclaimer: The fields in this API response are mock data generated for demonstration purposes and do not represent real operational metrics.

{
  "assetId": "urn:li:dataset:(urn:li:dataPlatform:hive,schema.table_A,PROD)",
  "healthStatus": "UNHEALTHY",
  "errorCategory": "UPSTREAM_ERROR",
  "context": {
    "upstreamAsset": "urn:li:dataset:(urn:li:dataPlatform:hive,schema.table_B,PROD)",
    "reason": "upstream data has not arrived for the expected data interval."
  },
  "lastCheckedAt": "2026-06-15T08:30:00Z"
}

From this response, the orchestrator can see that table_A is unhealthy because of an upstream dependency rather than a problem in the asset itself. It then traces the active DPI for the upstream asset and links the table_A DPI to that upstream issue. The downstream DPI can inherit the same owner as the upstream DPI, keeping related failures grouped under the team best positioned to resolve the root cause.

The DPI process works only when the issues it raises can be assigned and fixed. If DPIs are frequently noisy, duplicated, or difficult to act on, users will eventually learn to ignore them. Diagnostic accuracy matters because it keeps DPIs useful for the people who receive them. It also creates a forcing function for each data-producing platform to improve its diagnostics. To produce accurate RCA, platforms need to incorporate signals from their dependencies and surrounding systems, not just their own local failure state.

Grab operationalizes DPI diagnosis across its internal data platforms. Our ingestion platform, Hugo, is a primary example of this approach, as outlined in a previous tech blog. Hugo’s intelligent diagnosis architecture uses a three-layered system to automatically detect, analyze, and troubleshoot data pipeline failures within its domain, as shown in Figure 2.
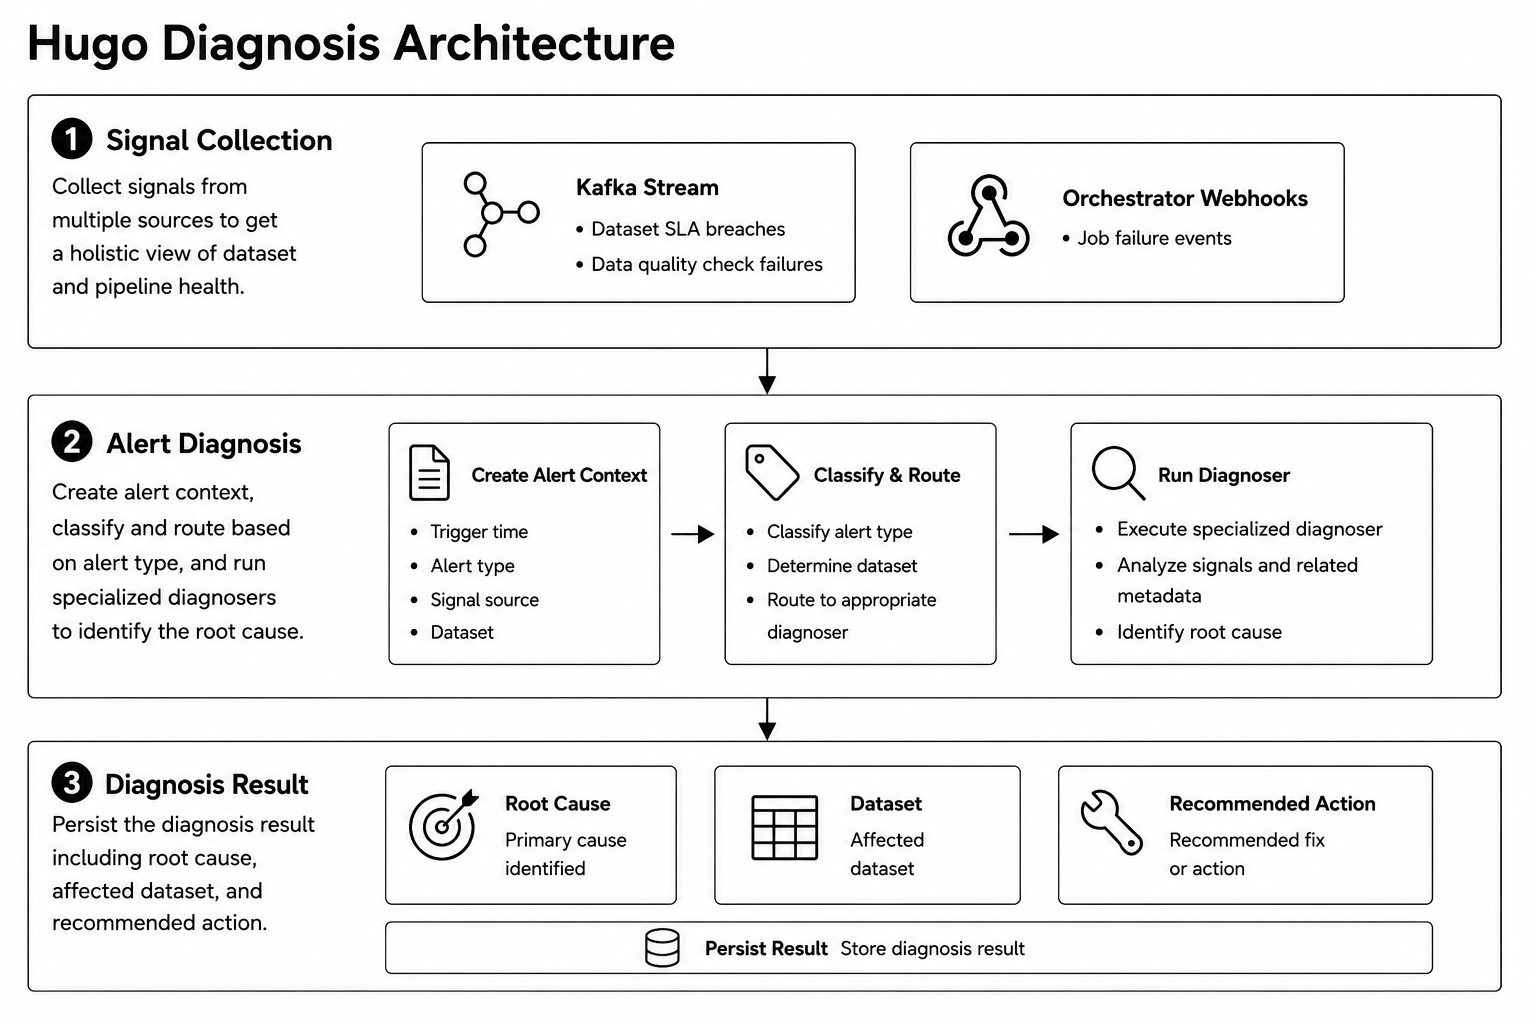
Diagram of Hugo's three-stage diagnosis architecture: signal collection, alert diagnosis, and diagnosis result.
Figure 2. Hugo diagnosis architecture.

Modern data platforms generate alerts from many independent systems. Individually, these signals show only a partial view of a dataset. Hugo consolidates platform-specific signals into a unified diagnostic workflow to pinpoint root causes and recommend pipeline remediations. The diagnosis architecture consists of three stages:

  1. Signal collection collects events from multiple signal sources to build a full view of the dataset and pipeline health.
  2. Alert diagnosis creates a structured alert context, classifies the alert, routes it to the appropriate diagnoser, and identifies the root cause using specialized diagnosis logic.
  3. Diagnosis result persists the structured diagnosis output, including the identified root cause, affected dataset, and recommended fix or action.

For example, when a dataset fails, the workflow orchestrator notifies Hugo with a job failure event. Hugo then routes the alert to its internal diagnostic layer to check for conditions such as upstream database replica lag, storing both the diagnosis and recommended fix alongside the affected dataset.

Decoupling signal ingestion, diagnosis, and result management makes it straightforward to add new signal sources and specialized diagnosers. Immediate RCA removes the need for manual log inspection, which shortens remediation and feeds directly into automated resolution workflows.

Resolving DPIs: Auto-healing first, human judgment when needed

After triage and RCA, the final stage of the DPI lifecycle is resolution. The lifetime of a DPI is a proxy for data downtime: it begins when a contract breach is detected and ends when the affected dataset becomes healthy again. Reducing that window requires more than identifying the correct issue. It also depends on recovering safely and consistently from recurring failure modes.

Many incidents are routine and recoverable, such as transient compute interruptions, database connection timeouts, S3 throttling, or upstream pipelines that are delayed rather than permanently broken. Instead of relying on manual intervention for every incident, Hugo automates recovery for these well-understood failure patterns. Once the diagnosis workflow identifies the root cause, it produces a structured diagnosis result containing the affected dataset, the root cause, and the recommended resolution strategy. The auto-resolution workflow then consumes this result to execute the appropriate remediation automatically. Figure 3 shows Hugo’s auto-resolution architecture in two stages.
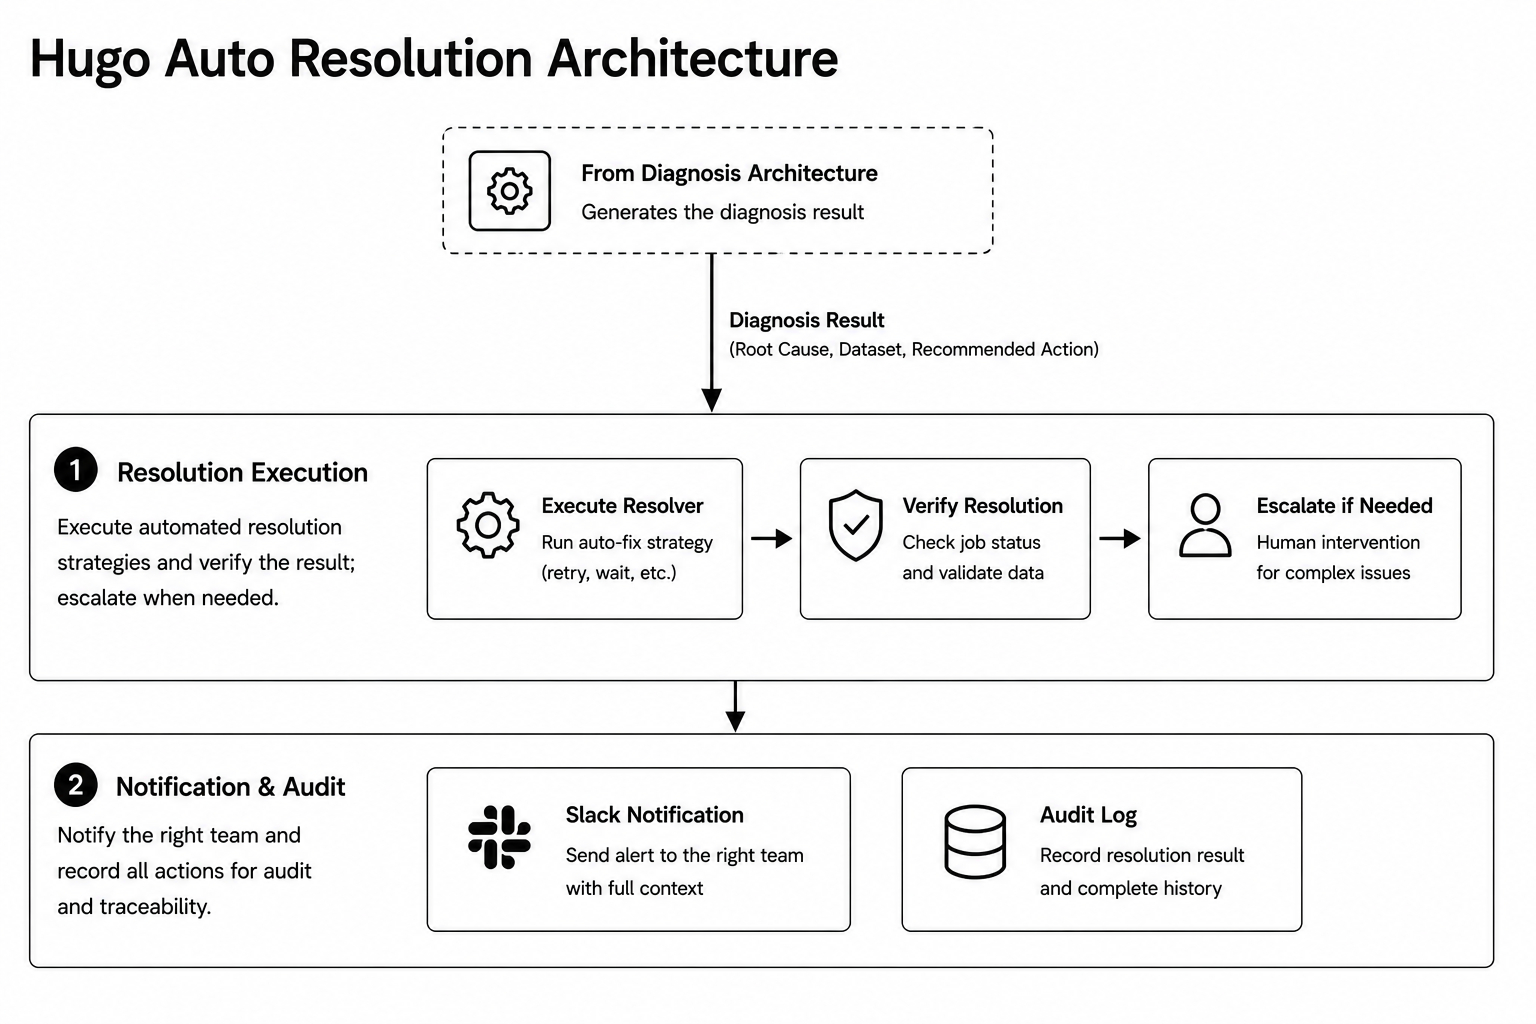
Diagram of Hugo's auto-resolution architecture, covering resolution execution plus notification and audit.
Figure 3. Hugo auto-resolution architecture.
  1. Resolution execution applies the recommended resolution strategy, such as retrying a failed job, waiting for an upstream dependency, or executing a custom resolver. After the action completes, the system verifies both pipeline health and data correctness to confirm the issue has been fully resolved. If a failure cannot be resolved safely through automation, such as in cases of data corruption, invalid records, or application code defects, the workflow escalates the incident for human intervention.

  2. Notification and audit records every resolution attempt and its outcome, while notifying the appropriate engineering teams. That record supports operational analysis, auditing, and later improvements to resolution policies.

For example, a dataset may miss its freshness Service Level Agreement (SLA) because the workflow orchestrator becomes temporarily unresponsive and fails to submit the scheduled ingestion job. The diagnosis workflow identifies the incident as a pipeline execution failure and recommends a retry strategy. Hugo automatically retries the job, verifies that the pipeline completes and data health is restored, then logs the recovery and notifies the responsible team. This end-to-end process, from incident detection to resolution, runs automatically without manual intervention.

Hugo closes the loop between detection, diagnosis, and recovery. Rather than stopping at identification, the platform turns diagnosis results into targeted remediation, so routine operational issues can be resolved automatically while preserving human oversight for complex or high-risk incidents. Separating diagnosis from execution also lets new diagnosis capabilities and resolution strategies evolve independently without changing the overall architecture.

The impact is already evident in production. 86.9% of DPI incidents were automatically resolved, significantly reducing manual operational effort. By automating routine recoveries, engineers spend less time performing repetitive operational tasks and more time building new platform capabilities, while overall data downtime is significantly reduced.

Conclusion

Certified data products still need to prove their reliability in production. Freshness delays, upstream failures, platform incidents, and data quality violations can all break consumer trust, even when an asset has already met certification standards.

Automated DPIs are the operating model for managing these failures. By turning contract breaches into structured production issues, the DPI lifecycle makes data reliability operational: triage separates real breaches from alert noise, diagnosis identifies the likely failure domain, ownership routing reduces handoffs, and resolution closes the loop through auto-healing or human intervention when needed.

The most important outcome is not simply that issues are detected faster. It is that data downtime becomes visible, measurable, and reducible. With every DPI tracked from detection to recovery, teams can understand where time is spent, which failure modes repeat, and where automation can safely reduce operational toil. To date, more than 95% of DPIs are raised automatically rather than by humans, with a mean time to resolve (MTTR) that is 6 times faster for automated DPIs than for manually raised ones.

For Grab, this shifts data reliability from reactive firefighting to a managed production workflow. Automated DPIs help keep trusted data products trustworthy after certification, so downstream teams can depend on them with greater confidence.

What’s next

Across the three-blog series, the story is how Grab turns data mesh from an operating principle into an artificial intelligence (AI)-ready foundation for the company.

  • Part I: Building trust through certification. Grab needed the Signals Marketplace because the business had scaled across mobility, deliveries, financial services, and many data-producing domains. The old model of relying on a central Data Engineering team could no longer keep up. Certification became the mechanism for making high-quality data products visible, reusable, and accountable. With clear ownership, data contracts, and measurable adoption, Grab moved more consumption toward trusted assets, reduced duplication, and created stronger incentives for teams to curate the data they publish.

  • Part II: The foundational tools behind certification. Trust becomes operational through platforms. Hubble covers discovery, lineage, ownership, and the certification engine. Genchi runs continuous data quality observability across freshness, completeness, schema, and business-rule checks. The Data Contract Registry formalizes producer-consumer expectations as versioned, enforceable contracts. Combined, these systems keep data certification an actively maintained standard rather than a static label.

  • Part III: Operationalizing data reliability with automated DPIs. Certification tells consumers which data products should be trusted; DPIs keep that trust true in production. Kinabalu evaluates contract breaches, deduplicates noisy alerts, assigns ownership, and tracks recovery. Data Health APIs make RCA portable across platforms, while Hugo’s diagnosis and auto-resolution patterns show how common failures can be remediated faster and with less operational toil. The result is a measurable reduction in time to resolve and a stronger feedback loop back into certification.

The bigger takeaway is that Grab’s data moat is not just the volume of data we have. It is the system that makes our data trustworthy, discoverable, reusable, and continuously reliable. This foundation is what lets us embrace the agentic world: AI agents can search certified assets, reason over contracts and lineage, trust quality signals, detect production issues, draft RCA, and eventually suggest or execute safe remediation. In that world, data reliability becomes a compounding advantage. The better our foundations are, the more confidently Grab can build agentic experiences on top of them.

We would like to thank all the data practitioners across Grab, including engineers and analysts to data scientists and product teams, who have invested in certification, contracts, and data quality to build a solid foundation for AI agents and AI-powered experiences. We are equally grateful for the unwavering sponsorship, strategic guidance, and hands-on support from our leadership (Mohan Krishnan and Nikhil Dwarakanath), without which this long-term data foundation initiative would not have been possible.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Crowdsourced taxonomy verification: A feedback-driven framework for refining knowledge graph relationships via online search interactions

Post Syndicated from Grab Tech original https://engineering.grab.com/crowdsourced-taxonomy-verification

Introduction

The efficacy of semantic search relies on the accuracy of the underlying Knowledge Graph (KG). In high-velocity domains like on-demand food delivery or e-commerce, the catalog of entities like dishes, products, and merchants changes rapidly.

Current methods for KG construction and maintenance face three critical challenges:

  • Inaccuracy and hallucination from Large Language Models (LLMs): Automated models often infer relationships based on statistical text co-occurrence rather than semantic reality. For instance, an LLM might incorrectly classify “Pho” as a child of “Italian Noodle Soup” due to linguistic similarity, leading to irrelevant search results.

  • Scalability limits of manual verification: Traditional verification relies on human annotators or domain experts. This approach is slow, expensive, and unable to keep pace with dynamic catalogs containing millions of entities. For example, daily changes in restaurant menus or grocery stock keeping units (SKUs).
  • Error propagation in ranking: Inaccurate graph edges propagate errors downstream. If a parent-child relationship is wrong, query expansion algorithms will retrieve irrelevant items, directly degrading Click-Through Rate (CTR) and user trust.

We introduce a feedback-driven verification engine that operationalizes the search interface as a validation environment. Key contributions include:

  • User feedback-driven verification: The system treats unverified graph edges as hypotheses. Instead of accepting them as truth, it tests them against live traffic by injecting them into search suggestions and measuring user engagement.

  • Hierarchical relationship refinement: Unlike systems that only validate entities (nodes), this framework validates structural links (edges). It confirms whether entity A is truly a parent, child, or sibling of entity B, ensuring structural integrity.

  • Adaptive exploration: The system employs a greedy exploration policy. It intelligently balances exploitation by showing known good results with exploration through injecting unverified candidates to gather data without degrading the user experience.

Background

Automated KG construction using LLMs and unstructured content extraction can scale quickly across large, dynamic catalogs. However, relationships inferred from text co-occurrence or vector similarity do not always reflect semantic reality. Manual verification by domain experts remains accurate but does not scale to millions of entities that change daily.

When inaccurate edges enter the graph, ranking and query expansion systems propagate those errors to users. Incorrect parent-child or sibling links lead to irrelevant search results, reduced CTR, and lower user trust. An additional solution is required that can validate graph structure continuously, at scale, without relying solely on manual curation.

Solution

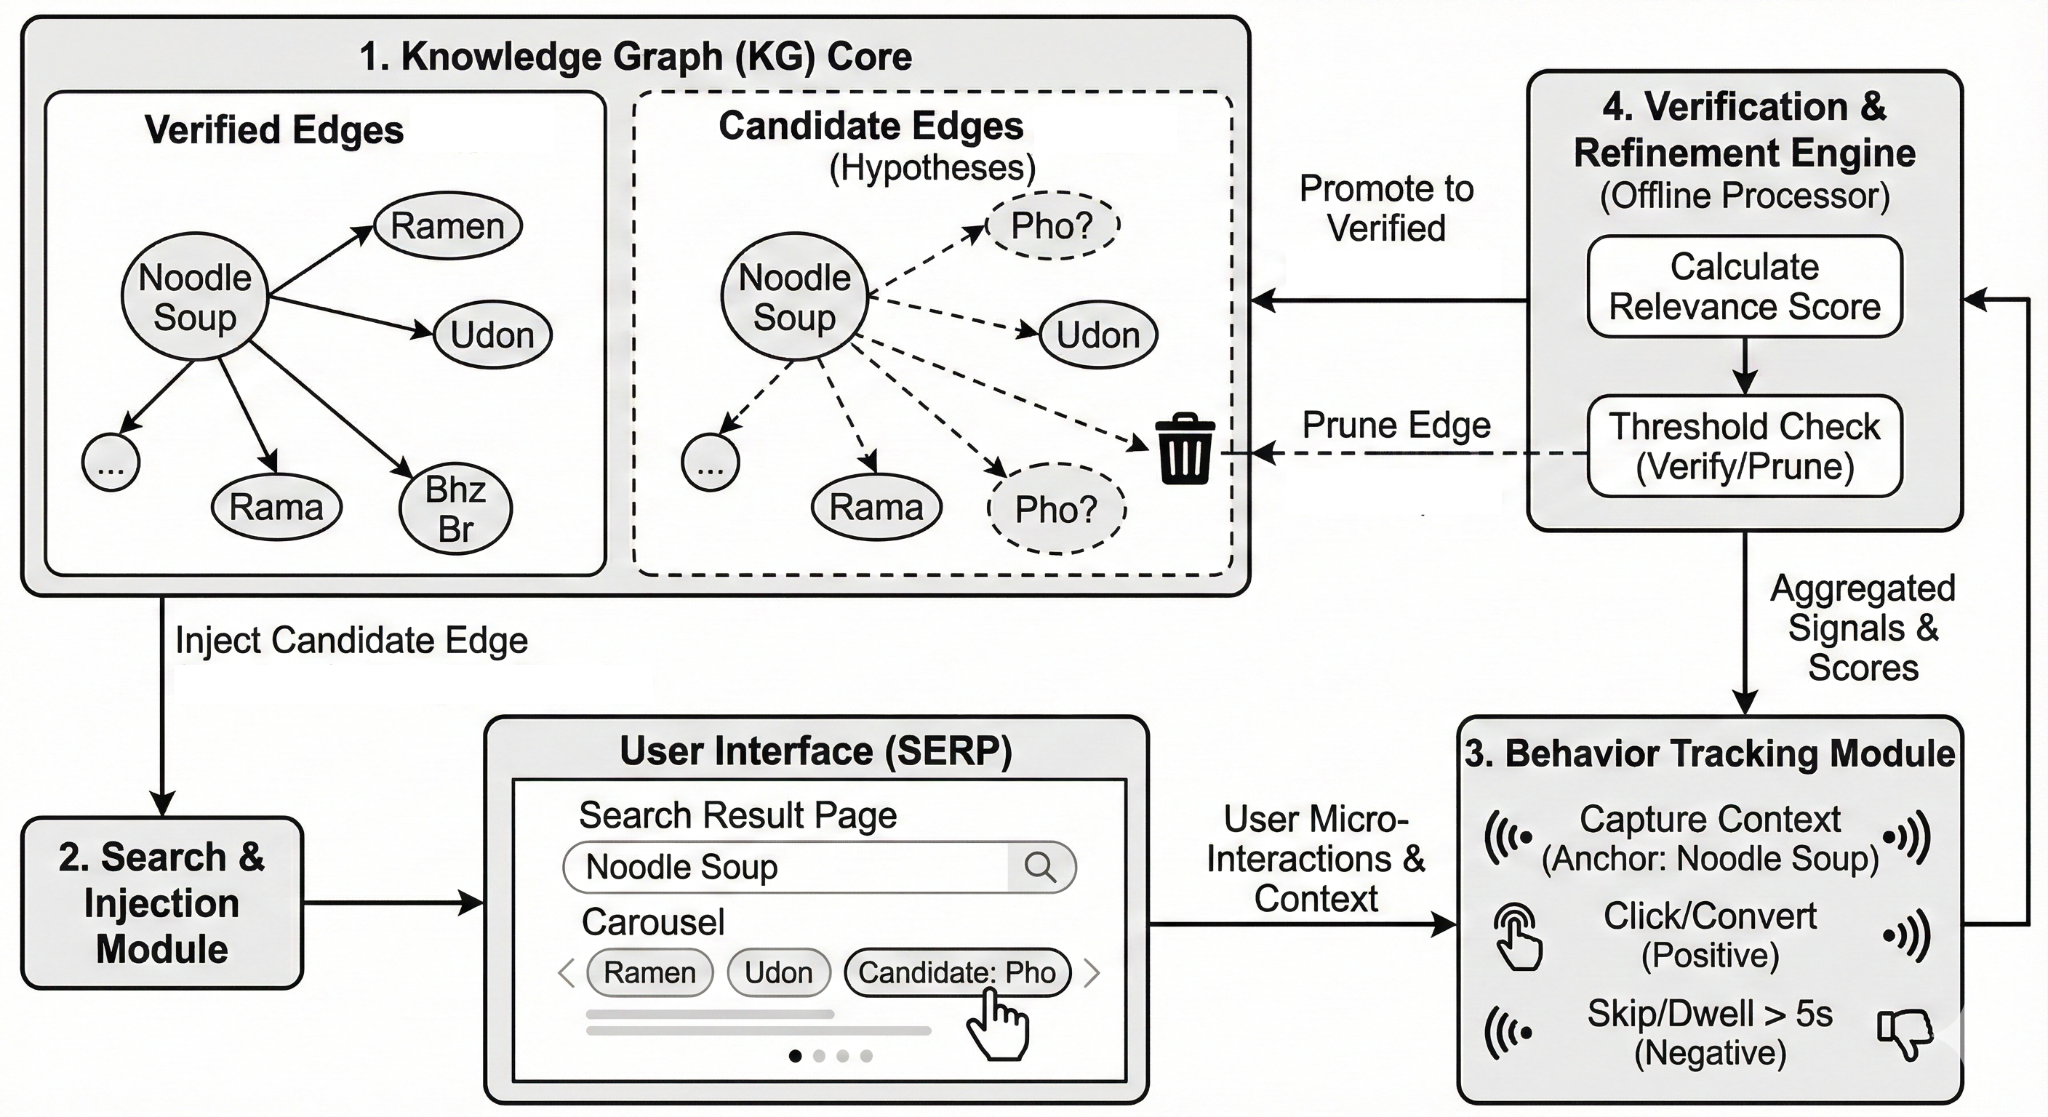
The overall workflow of this invention is shown in the following figure. The details of each step are explained in this section.

Figure 1. The system architecture.

The proposed framework functions as a closed-loop validation ecosystem. It is composed of four integrated modules designed to continuously cycle data from the KG to the user interface and back, using real-world interactions to separate semantic truth from artificial intelligence (AI) hallucinations.

The verification process follows a continuous, iterative loop that cycles data from the backend graph to the frontend user interface and back. This four-step procedure operationalizes the human-in-the-loop validation mechanism:

  1. Hypothesis generation
  2. Candidate injection
  3. Signal aggregation and scoring
  4. Graph update logic

Architecture details

KG core

The central repository acts as the source of truth, storing entities such as dishes, products, or merchants, and the connections between them. To manage the verification process, the system introduces a specialized metadata layer that classifies every connection (or edge) into one of two distinct states:

  • Verified edges: These are established relationships that have been validated either by high historical traffic or human confirmation. They represent the safe structure of the graph. For example, “Sushi” is definitely a child of “Japanese Cuisine”, and is used to power standard search results.
  • Candidate edges: These are probabilistic, unverified relationships generated by automated LLMs or content scrapers. They are treated as hypotheses waiting to be proven. For example, if an LLM ingests a blog post and predicts that “Pho” is related to “Italian Noodle Soup,” this link is stored as a candidate edge, invisible to the main search algorithm until validated.

Search and injection module

This module sits between the KG and the user, intercepting the query execution pipeline. Unlike standard ranking algorithms, which strictly optimize for relevance by showing only the best results, the injection engine employs a balanced strategy known as exploration vs. exploitation.

  • The injection mechanism: When a user performs a search, the system retrieves a list of high-confidence results (exploitation). Simultaneously, it deliberately retrieves a small subset of candidate edges related to the query. It injects these unverified candidates into specific, lower-risk slots within the user interface, such as the third or fourth position in a related searches chip carousel.
  • Risk management: To prevent user frustration, the system limits the number of candidates shown per session. This ensures that the user is primarily served helpful, verified content, while still providing enough data points to test new hypotheses.

Behavior tracking module

To accurately measure whether a candidate relationship is valid, the system tracks user micro-interactions with high granularity. It captures not just the final click, but the precise context in which the interaction occurred to determine semantic intent.

  • Contextual anchoring: The system logs the specific search term, also known as the anchor, used by the user. A click on “Pho” is only counted as a vote for the relationship if the user was searching for “Noodle Soup” at the time.
  • Signal classification: Signals are assessed in aggregate to estimate the relevance of a candidate relationship. Higher-intent engagement contributes stronger positive evidence, lighter exploratory behavior contributes weaker positive evidence, and lack of engagement or explicit negative actions contributes negative evidence.

Verification and refinement engine

This is an offline processing unit that acts as the final judge. It aggregates thousands of individual user signals to update the topology of the KG.

Relevance scoring: Instead of complex formulas, the engine calculates a simple confidence ratio. It looks at the total number of times a candidate was shown versus the number of positive interactions it received.

Graph topology updates:

  • Promotion (verify): If the confidence ratio exceeds a verification threshold. For example, if the candidate performs as well as known good items, the edge is upgraded from candidate to verified. It becomes a permanent part of the graph and is shown to all users.
  • Demotion (prune): If the candidate consistently fails to garner engagement or receives negative signals, it falls below a pruning threshold. The system automatically deletes this edge, effectively correcting the AI’s hallucination and cleaning the dataset.

Implementation

Hypothesis generation

The process begins by identifying a target subject, referred to as the anchor entity. For example, the specific dish “Pho”. The system queries the KG to retrieve a set of potential relationships. This retrieval includes both verified neighbors, where relationships are already confirmed by experts, and candidate neighbors, where the relationships are predicted by AI models but not yet proven.

Candidate injection

Once a hypothesis is selected, the system exposes it to real users to gather evidence. When a user actively searches for the anchor entity, the system dynamically injects the candidate neighbor into the search results.

  • User interface (UI) implementation: The candidate is presented alongside verified items, typically in a related categories carousel or a refine search chip list. This reflects standard relevance experimentation in search, with safeguards to ensure the experience remains controlled and measurable.
  • Exposure logging: The system logs an impression event specifically linking the anchor to the candidate. This record serves as the baseline, documenting that the user saw the relationship, which is essential for calculating future engagement rates.

Signal aggregation and scoring

Instead of using a raw count of clicks, the system calculates a sophisticated relationship confidence score by aggregating user interactions over time. This scoring model uses a weighted tier system to distinguish between casual interest and strong intent.

  • Weighted interaction logic: The system assigns a higher value to actions that require more effort or commitment. For example, a “Purchase” or “Add-to-Cart” action is weighted significantly heavier than a simple click, as it indicates a strong validation of the relationship. Conversely, scrolling past the item quickly or skipping is treated as a negative signal.
  • Normalization: To ensure fairness, the total weighted score is normalized against the total number of times the candidate was shown. This prevents niche items with low total traffic but high accuracy from being unfairly penalized.

Graph update logic

Periodically, the verification engine evaluates the confidence score against predefined benchmarks to update the KG’s topology. This is a binary decision process:

  • Validation (cementing the edge): If the accumulated confidence score exceeds a strict validation threshold, the system concludes that the relationship is genuine. The status of the edge is updated from candidate to verified. This permanently adds the relationship to the graph, ensuring it appears in future standard searches without the need for further testing.
  • Rejection (pruning the edge): Conversely, if the score falls below a rejection threshold, indicating that users consistently ignore or reject the suggestion, the system concludes the relationship is an AI hallucination. The edge is severed or removed from the graph. This pruning action cleans the dataset, preventing the system from making the same bad recommendation again.

Case study: hierarchical refinement in food delivery

To demonstrate the framework, consider a validation scenario in food delivery taxonomy. An LLM-based ingestion pipeline flags a candidate parent-child link
Noodle Soup → Dry Mee Pok and stores it as an unverified candidate edge in the KG, ready for live validation.

User-triggered validation:

When a user searches for “Noodle Soup,” the search module injects the candidate alongside verified results. For example, in a “Refine by Dish” filter carousel, and logs an impression linking the anchor query to the candidate.

Outcome collection:

User interactions like clicks, dwell time, scroll behavior, and conversions are captured and weighted over the validation window. The verification engine aggregates these signals and updates the graph: relationships that meet the validation threshold are promoted to verified status; those that fail are pruned or re-mapped to a more appropriate parent node.

Impact

By injecting unverified candidate edges into live search results and recommendation interfaces via a multi-armed bandit (MAB) exploration strategy, the system leverages implicit user feedback to validate semantic truth. This dynamic, human-in-the-loop mechanism effectively prunes erroneous connections and reinforces accurate taxonomies without the need for manual curation, significantly enhancing search relevance in dynamic domains such as food delivery and retail.

The case study demonstrates how the framework validates candidate relationships through live user traffic, collecting interaction signals and updating the graph without manual curation.

Learnings and conclusion

The feedback-driven verification engine operationalizes the search interface as a validation environment for KG relationships. By classifying edges as verified or candidate, injecting candidates through an exploration vs. exploitation strategy, and aggregating weighted user signals, the system promotes accurate relationships and prunes AI hallucinations at scale.

Unlike approaches that validate only entities, this framework validates structural links, confirming whether entity A is truly a parent, child, or sibling of entity B. The food delivery case study shows how a user-triggered search can initiate validation and outcome collection at scale, without manual intervention.

What’s next

Hierarchical confidence tiers

To safely graduate new connections into the production graph, we are introducing a dual-measurement trust system that requires both volume and variety before a new connection goes live: support mass (product hits, graph depth, recency) and corroboration (unique sessions, anonymous cohorts, and temporal spread). Connections must climb a strict state machine: proposed → shadow eligible → canary eligible → production, advancing only when both metrics meet progressively higher thresholds; if a snapshot causes metrics to fall below a tier’s floor, the connection is automatically demoted.

Adversarial and spam resistance

To prevent bad actors, bots, or highly repetitive users from manipulating the search graph, we are building a multi-layered defense system. We enforce per-merchant rate limits and anti‑abuse controls: hourly caps per session/device, exponential backoff for rapidly repeated actions, and a short (few‑hour) freeze of promotions from any user cohort after declines or “irrelevant” signals. For bot and Sybil attack defense, traffic flagged by abuse systems is excluded from trust calculations (but logged for analysis); votes must come from diverse network subnets or cohort buckets, and each bucket is subject to a daily contribution cap.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Scaling Grab’s Data Lake: Our journey to Apache Iceberg adoption

Post Syndicated from Grab Tech original https://engineering.grab.com/our-journey-to-apache-iceberg-adoption

Introduction: The evolution of Grab’s Data Lake

At Grab’s scale, managing petabytes of data across billions of S3 objects demands more than a storage layer. It demands a robust architectural primitive that supports the high-concurrency needs of a modern “Lakehouse.” Our goal is full storage-compute separation, leveraging S3 as an elastic foundation for both near-real-time metrics and large-scale batch transformations.

For years, the vast majority of our tables were Hive Parquet, managed through the Hive Metastore with a directory-based layout. This model served us well, but as data volume grew, the directory-and-metastore approach became the limiting factor. We are now transitioning to a table-centric architecture built on modern table formats, treating data as a first-class primitive to ensure consistency and performance across our internal data transformation platforms: Slide, which powers batch transformations, and Hugo, which handles online-to-data-lake ingestion. Along the way, we also built the UnifiedSparkCatalog, a unified Spark catalog that hides table-format differences from users entirely, which we are open-sourcing alongside this post.

The catalyst for change: Challenges with Hive Parquet

For years, Hive Parquet was the backbone of our Data Lake, representing the vast majority of our tables. However, as data volume scaled, the architectural limitations of directory-based storage became apparent. We identified four primary bottlenecks:

  • Catalog latency: The Hive Metastore (HMS) became a centralized failure point. High concurrency during metadata access led to O(n) listing overhead, where query planning time scaled linearly with partition count, crippling throughput.
  • The small file problem: The directory layout left us with severe file fragmentation. Certain Machine Learning (ML) datasets had an average file size under 1 MB, with thousands of files in each partition. At this scale, the overhead of S3 object listing and metadata request latency drove up Application Programming Interface (API) costs and slowed scan operations.
  • Operational toil: Data engineers faced constant manual overhead for partition registration. Without native ACID support (no native UPSERT or DELETE), teams relied on complex workarounds to manage data changes carefully.
  • The broken information loop: A fundamental disconnect existed between the catalog and storage. Because the HMS, not the storage layer, was treated as the source of truth, direct S3 modifications frequently left the catalog stale and out of sync with the actual state on disk.

Why Iceberg? Strategic alignment and future-proofing

We evaluated several open table formats before selecting Apache Iceberg as our default. The deciding factors came down to community governance, engine compatibility, and long-term flexibility.

Recent industry momentum, including growing cloud-native support for Iceberg, further validates this direction. We are positioning Grab to be format-agnostic in the long term, but Iceberg provides the most mature foundation today.

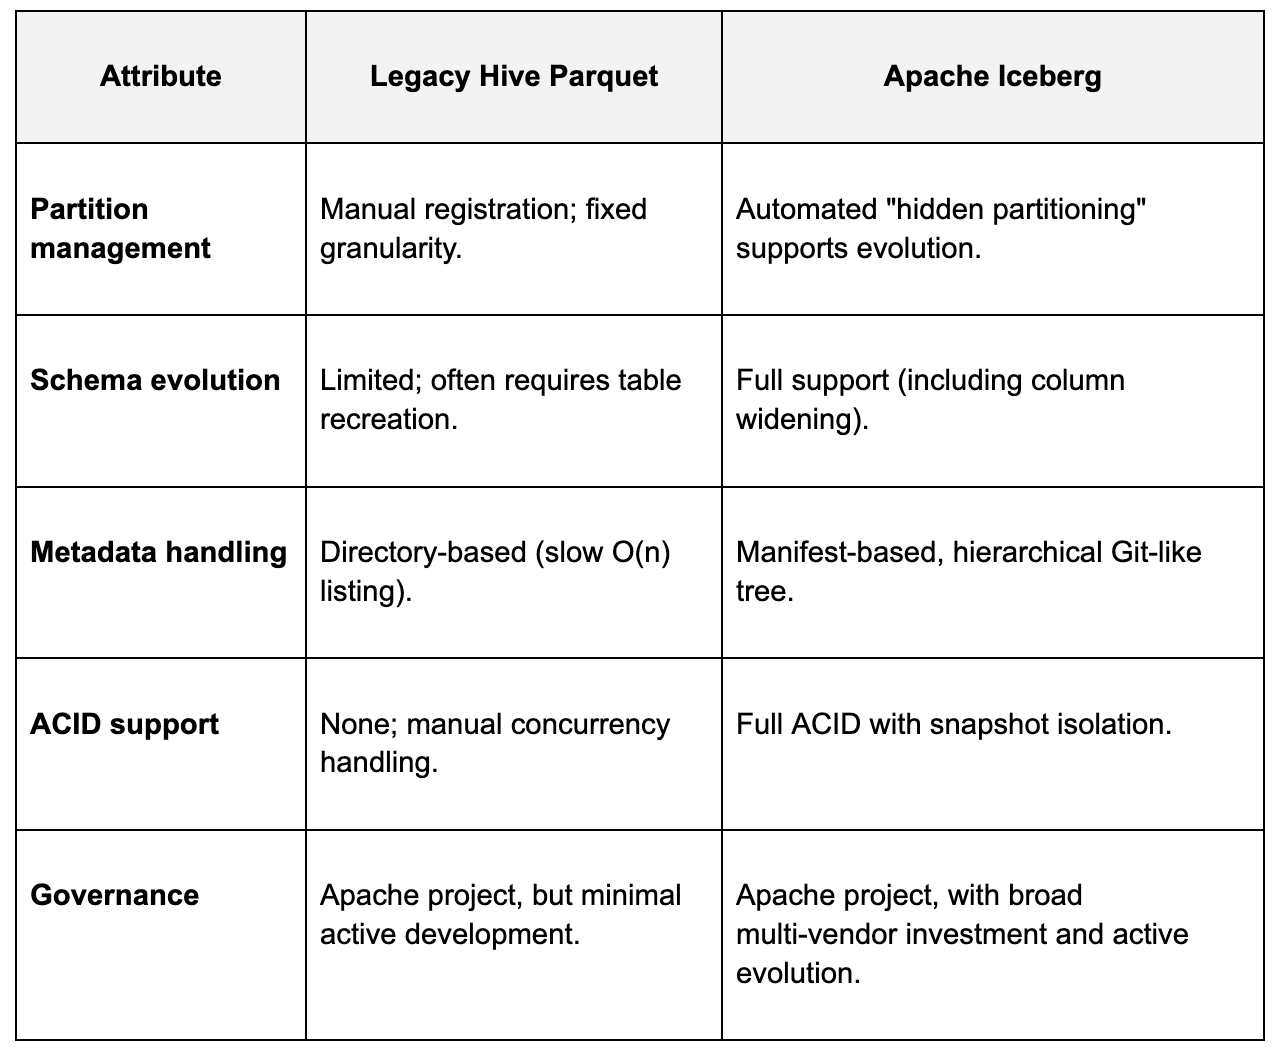
Comparison of Legacy Hive Parquet and Apache Iceberg

Adopting Iceberg at scale

Migrating an established lake is not a flag flip. Our challenge was rolling out Iceberg across a lake that was overwhelmingly Hive Parquet, queried by many engines and teams, without breaking the downstream consumers that depended on those tables. Rather than converting everything at once, we moved the highest-value tables first. The efficiency gains across our production workloads have been substantial. Here are representative examples:

  • Query performance via Z-ordering: On a high-traffic navigation dataset, we achieved roughly a 10x improvement in query runtime. Z-ordering co-locates rows with similar values across specified dimensions, enabling Trino to leverage data skipping and min/max statistics to prune irrelevant files during query planning. This reduced query runtime from 70 seconds to 6 seconds.
  • S3 API cost reduction: For a heavily queried operations table, daily S3 API costs were reduced by up to 95% with no changes to the queries themselves. Larger file sizes and the elimination of expensive object listing during query planning drove most of the savings.
  • Compute savings: For a dataset used in funnel analysis, we reduced cluster resource usage by approximately half. A separate ML feature pipeline also improved feature freshness for downstream models.

The UnifiedSparkCatalog: Making mixed formats transparent

Migrating to Iceberg solved our storage and metadata problems, but it surfaced a new one at the developer-experience layer. Modern table formats like Delta, Iceberg, and Hudi each implement their own custom catalog that extends Spark’s SessionCatalog. In a standard Spark runtime, only one catalog implementation can be set as the default spark_catalog. Supporting additional formats requires explicit catalog declarations, meaning users must reference tables with format-specific prefixes like iceberg_catalog.schema.table or delta_catalog.schema.table.

With Iceberg, Delta, Hudi, and Hive tables now coexisting and tables actively migrating between formats, this created two problems: engineers had to know the underlying format of every table they queried, and any format migration silently broke every downstream query that hardcoded a prefix.

The UnifiedSparkCatalog is our answer. It is a unified Spark catalog that abstracts the complexity of working with mixed table formats so users never need to think about which format a table uses. We took inspiration from Trino’s Table Redirection, a feature that transparently points a query at the right connector when a table’s format differs from the catalog it was queried through. Our Spark equivalent works as follows:

How it works

  1. Table detection: The catalog loads metadata from the Hive Metastore.
  2. Format identification: A TableTypeDetector utility identifies the format based on metadata properties (e.g., the provider field) or path-based inference.
  3. Operation routing: The catalog delegates the operation to the correct format-specific catalog (Iceberg’s SparkCatalog, Delta’s DeltaCatalog, etc.) without requiring any prefix from the user.

Key design decisions

  • Lazy initialization: Catalogs for each format are initialized only when first needed, reducing startup overhead. If a format’s JAR is missing from the classpath, initialization continues gracefully. The catalog simply skips that format rather than failing the entire session.
  • Naming as spark_catalog: The catalog reports its name as spark_catalog because Spark treats this name specially for legacy Hive Data Manipulation Language (DML) operations. Many internal Spark code paths check for this exact name to determine whether to use Hive-compatible logic for inserts, updates, and deletes. Using any other name would break legacy Hive table operations.
  • Catalog reuse: Before creating a new catalog instance, the system checks whether one already exists in Spark’s catalog manager. This preserves compatibility with plugins like OpenLineage, which inspect catalog class types for lineage extraction.
  • Fallback behavior: If a table is not found in the expected format-specific catalog, the system falls back to the base session catalog, ensuring robust behavior for standard Hive tables.

We are open-sourcing UnifiedSparkCatalog alongside this blog post. The code and documentation are available here.

Lessons learned and overcoming hurdles

Scaling Iceberg across a large ecosystem revealed several technical nuances:

  • Hive lock contention: We encountered “zombie locks” in the HMS that blocked commits. We traced this to a low read timeout on the metastore side under high load. Adjusting retry intervals and increasing the timeout resolved the issue.
  • Timestamp handling: Spark 3.4 introduced TIMESTAMP_NTZ (no time zone), while Iceberg defaults to TIMESTAMP_LTZ (local time zone). This caused compatibility issues with legacy Hive views. We resolved it through a custom migration workflow and targeted patches to our Trino deployment to ensure consistent casting.
  • Storage tier costs: Generating Iceberg metadata involves reading historical data, which can trigger a one-time cost spike as files move between S3 storage tiers. To manage this, we prioritize migrations based on a table’s scan frequency and API operation costs rather than migrating the entire lake at once.

Conclusion: The road ahead

Apache Iceberg is now foundational to Grab’s data strategy. It is the default format for Slide and Hugo, and adoption is expanding across our compute platforms.

Looking forward, we are experimenting with Storage Partitioned Joins to eliminate shuffle stages in Spark and monitoring the Apache XTable project to maintain interoperability between formats. Our journey does not end with adoption. We will continue contributing back to the ecosystem, starting with the upcoming release of the UnifiedSparkCatalog.

Acknowledgments: This journey was made possible by the dedicated efforts of the Data Engineering, Infrastructure, and Search & Personalization teams at Grab.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
The Hugo evolution: Engineering Grab’s unified, one-click data ingestion platform with Apache Flink

Post Syndicated from Grab Tech original https://engineering.grab.com/one-click-data-ingestion-platform-with-apache-flink

Introduction

Data drives every decision we make at Grab. As our operations scale, so does our need for robust, real-time data ingestion and processing frameworks. Enter Hugo: our self-service data platform that has long empowered teams to seamlessly route data into our Data Lake. Today, Hugo is evolving. We have taken previously siloed onboarding workflows and transformed them into one seamless, unified journey to truly democratize data ingestion and maximize efficiency.

In this blog, we’ll share how Hugo turns complex engineering hurdles into a frictionless, self-service reality. By moving away from siloed workflows, we’ve achieved a unified pipeline experience where one-click RDS CDC and self-service Kafka ingestion are the new standard.

Background

Figure 1. Hugo – Ingests data from every source into Grab’s data lake.

Hugo was originally designed as a self-service platform for batch-oriented data ingestion into the Data Lake, built on a single computation engine, Spark. It provided a centralized and streamlined onboarding experience for data sources such as MySQL, Aurora, PostgreSQL, and DynamoDB.

As the organization’s data platform evolved toward near real-time ingestion, Hugo expanded to support streaming pipelines from Kafka and MySQL binlog. This evolution introduced a more distributed architecture, where ingestion workflows spanned multiple systems, including Kafka Connect, Sprinkler (an in-house Go-based S3 writer), and Hugo.

The siloed past: A multi-platform hurdle

While powerful, the expanded architecture introduced significant onboarding friction. Creating a single data pipeline now requires users to coordinate across multiple platforms, each with its own configuration model and operational semantics. As a result, the onboarding journey became fragmented and difficult to navigate, especially for new users.

The common challenge during onboarding was helping users understand how configurations mapped across systems.

For MySQL CDC pipelines, users often asked, “I’ve already configured Kafka Connect, what values do I need to provide in Hugo?” after setting up a Kafka Connect job. This revealed a gap in abstraction between systems, requiring users to manually translate concepts and configurations across different platforms.

For Kafka pipelines, users frequently struggled with schema evolution in the data lake. Common questions included: “How should I update the data lake schema?” and “I’ve already updated the Protobuf schema for this Kafka topic, why isn’t the latest schema reflected in the data lake?” These issues highlighted unclear expectations around schema propagation and synchronization across the pipeline.

This multi-step, cross-system dependency increased cognitive load, slowed down onboarding, and created coordination overhead between platform teams and users.

The Hugo evolution: A unified ingestion platform

Hugo’s new, deeply automated ingestion framework, built with a custom automation layer and Apache Flink, has unified workflows and retired Sprinkler and Kafka Connect. This evolution converted manual, artisanal work into a streamlined, self-service experience, with custom automation serving as the “intelligent chassis” for the entire user journey.

The Hugo ingestion architecture: Engineering a unified flow

One-click MySQL CDC pipelines

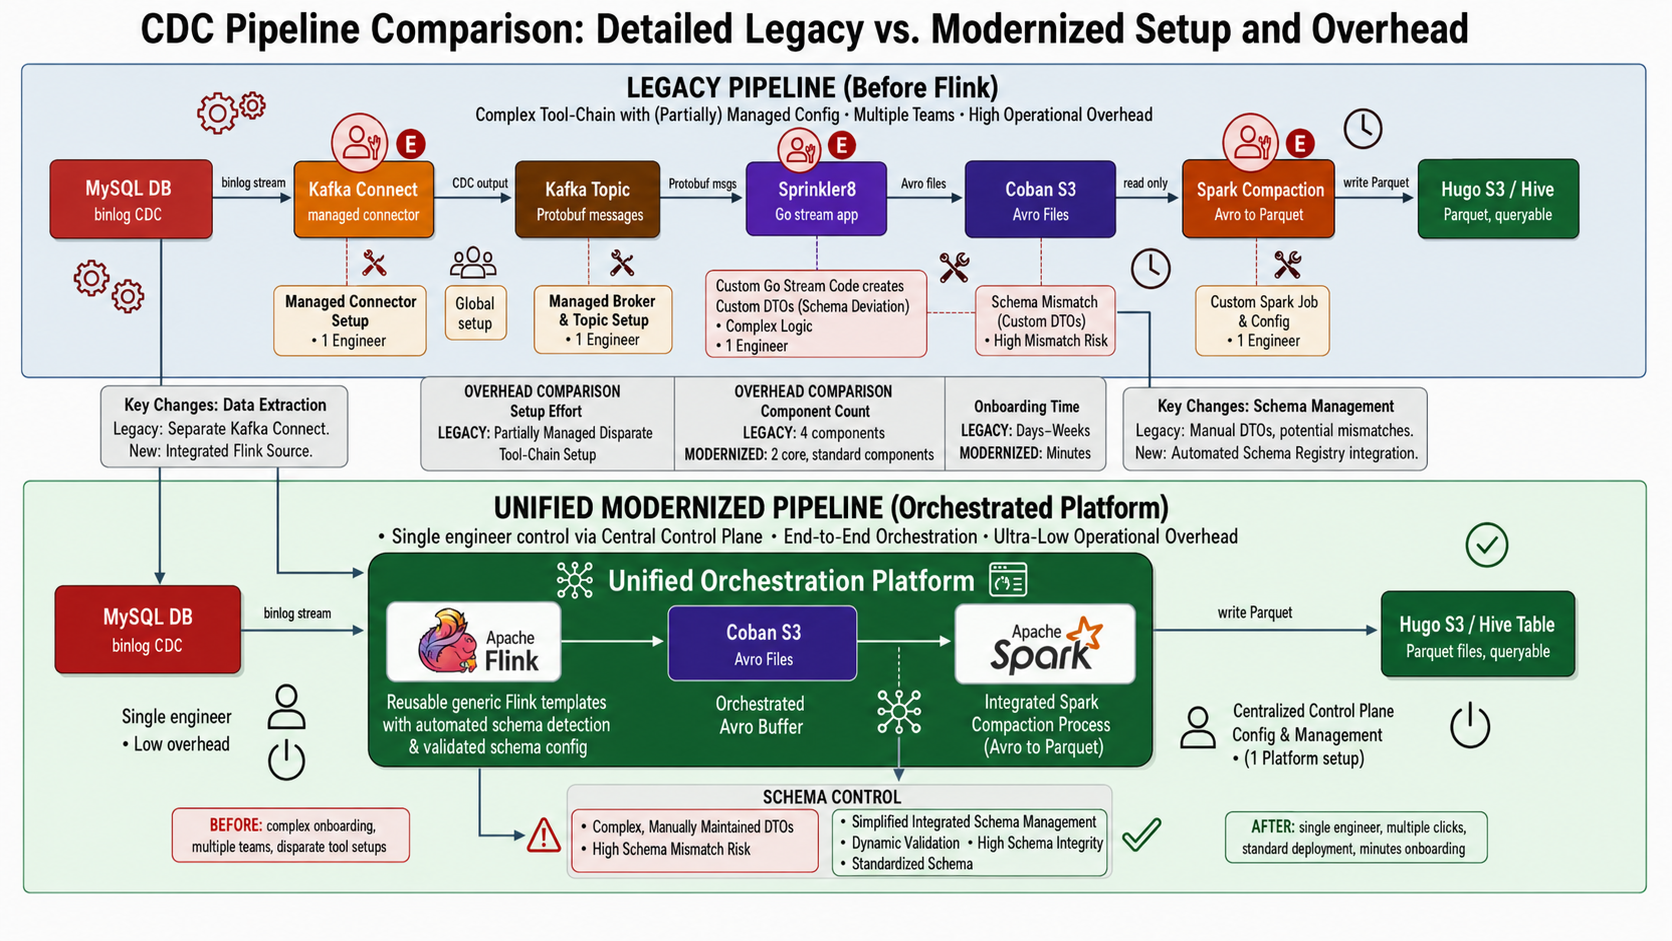
The transition to a unified modernized pipeline powered by Flink CDC shifts the data ingestion architecture from a fragmented, high-maintenance toolchain into a single, end-to-end orchestrated platform. By reading the database binlog directly and embedding the lifecycle within a centralized control plane, the modernized approach drastically reduces operational overhead, eliminates data mismatch risks, and cuts onboarding times from days to minutes. Below are the core advantages of adopting Flink:

  • Minimal operational overhead: It reduces the footprint from 4 disparate components (Kafka Connect, topics, Sprinkler app, and Spark) to just 2 core components managed via a single control plane.
  • Eliminated schema risk: It replaces brittle, manually coded Go DTOs, which caused frequent schema deviations, with automated schema detection and dynamic validation.
  • Streamlined architecture: It eliminates the intermediary Kafka hop. Flink reads the MySQL binlog directly and pushes straight to a queryable Hive table via an integrated Spark compaction process.
  • Instant onboarding: It shifts deployment from a multi-team, ticket-heavy process taking days to a single-engineer, self-service setup completed in minutes.
Figure 2. Data ingestion with MySQL CDC to data lake

Self-service Kafka ingestion

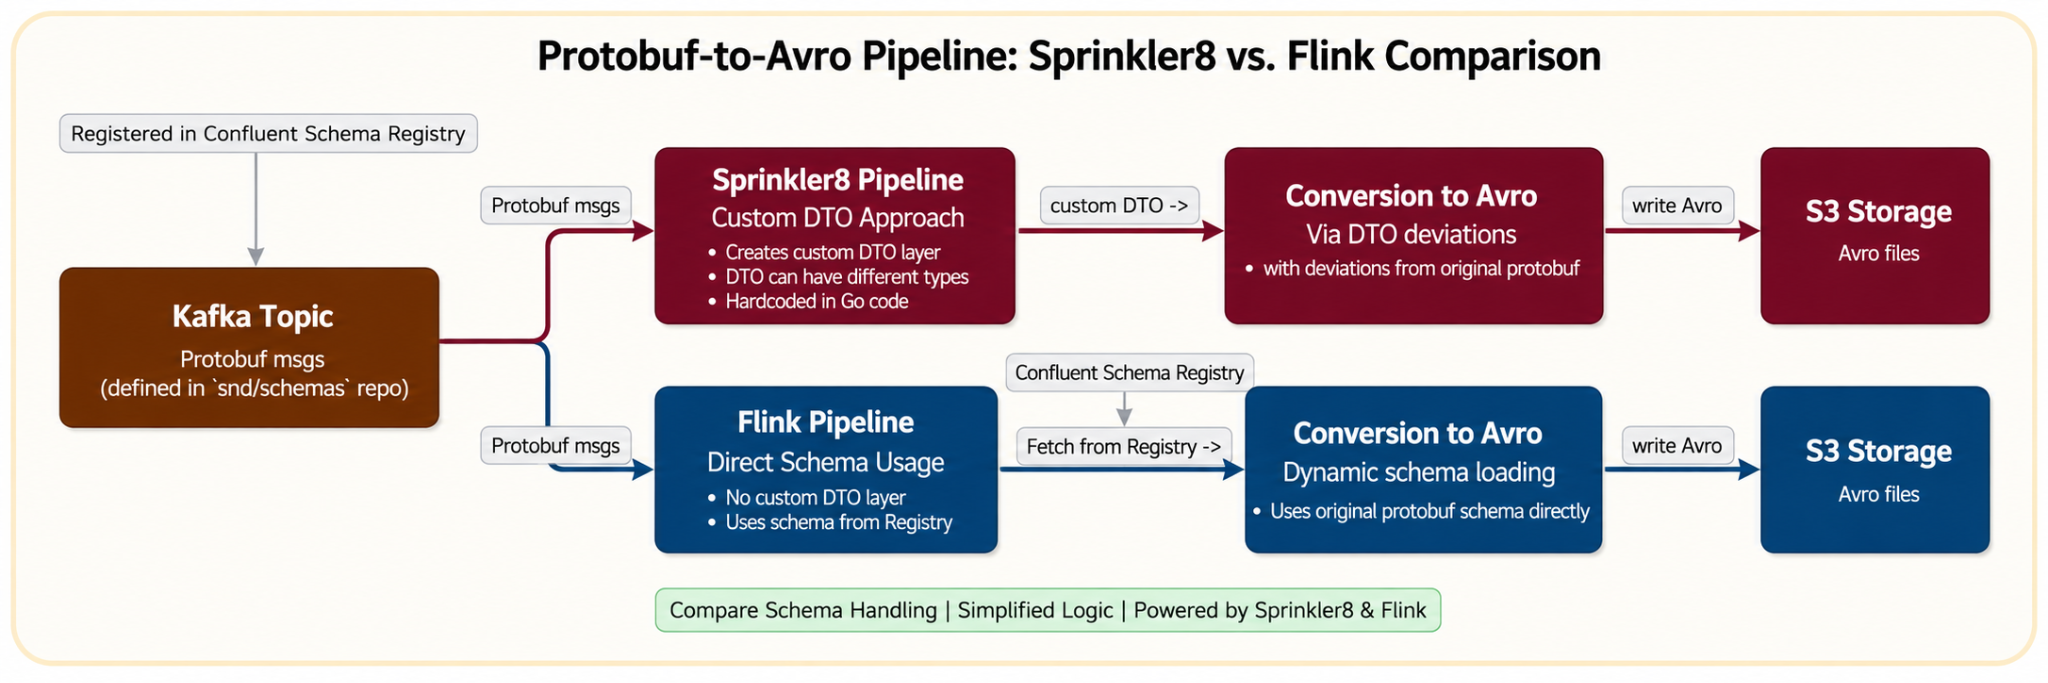
The most significant architectural shift in the self-service Kafka ingestion pipeline is the move from manual, fragile schema handling to an automated, resilient system. This comparison highlights the operational pain points eliminated by adopting Flink’s approach.

Legacy Sprinkler approach (manual and static)

  • Static registration and hardcoding: It required manual registration of streams within the Go monorepo and relied on hardcoded mappings in entities.go to convert Protobuf to Avro.
  • Custom dependencies: Avro schema was generated indirectly from custom DTO structs, not directly from the Protobuf definition.
  • Manual schema evolution: Any field change required a multi-step manual process: updating .pb.go and entity files, followed by a manual pipeline rebuild.

New Flink approach (automated and dynamic)

  • Dynamic runtime fetching: Flink pipelines dynamically retrieve the Protobuf schema from Confluent Schema Registry on startup, removing the need for hardcoding and manual stream registration.
  • Reduced operational overhead for schema changes: Schema updates are propagated through the CI pipeline to the Schema Registry, removing the need for hardcoded mapping changes. The Flink pipeline can detect updated schemas and resume from the latest checkpoint after restart, though manual restart intervention is still required.
  • Click-to-query: Engineers can now ingest streaming data from Kafka topics into queryable Hive tables through a few clicks in the Hugo UI. Hugo automatically orchestrates the multi-stage background work, from Flink consumption and S3 writing to Spark compaction, ensuring data is query-optimized and ready for immediate use.
Figure 3. Data ingestion with Kafka to Datalake.

Impact

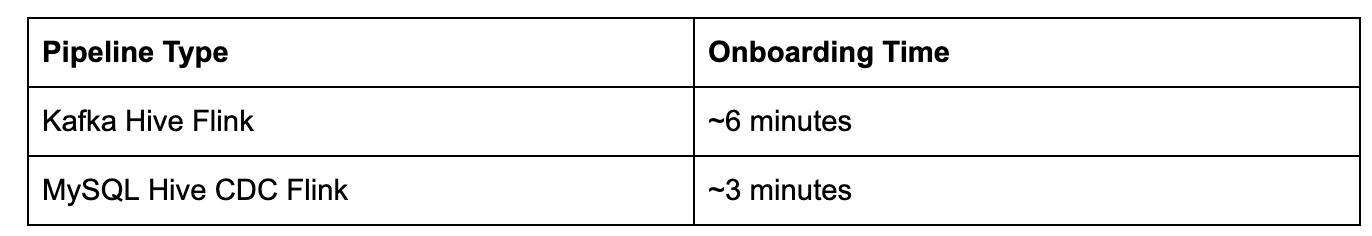
The platform’s new onboarding workflow has significantly reduced a previously multi-day process to mere minutes, enabling faster iteration and improving overall onboarding efficiency. This dramatic change has fundamentally altered how our teams interact with data.

Figure 4. Kafka Flink.
Figure 5. CDC Flink.

The onboarding workflow is intentionally designed with early validation guardrails to proactively surface prerequisite and governance-related issues before pipeline creation proceeds.

  • For Kafka sources, user drop-offs between the “Create Kafka Source” and “Kafka Sink” stages are primarily driven by validation checks such as topic ownership verification and topic activity requirements, for example topics with zero message volume. Additional drop-offs between the “Kafka Sink” and “Create Source Pipeline” stages typically occur when the proposed output table name already exists in the data lake, preventing duplicate table creation.
  • For MySQL sources, drop-offs are mainly associated with unmet database onboarding prerequisites, including credential setup, binlog user configuration, binlog format requirements, and binlog expiration settings.

In addition, the streamlined self-service experience encourages exploratory usage, allowing teams to familiarize themselves with the onboarding workflow and platform capabilities before fully committing to pipeline creation.

Summary

The new architecture engineered a custom automation layer that successfully retired the reliance on Kafka Connect and Sprinkler for the data lake, turning artisanal work into a streamlined, one-click experience. This transformation provides a direct boost to developer productivity.

The key impact metrics are:

  • Onboarding time reduction: The time required to set up data pipelines has been dramatically reduced and is now measured in minutes.
    • Kafka pipelines: approximately 6 minutes.
    • MySQL CDC pipelines: approximately 3 minutes.
  • Adoption: Since the release, the number of new Kafka and CDC pipelines onboarded in the last year is more than the total number of pipelines onboarded in the previous five years.

What’s next

These enhancements are just one step in our broader vision for optimized and self-service data ingestion. Currently, Flink is the default only for Kafka source pipelines. Flink onboarding for MySQL CDC pipelines is impact- and cost-driven. Our strategic roadmap includes:

  • Next-generation formats: We are investigating the adoption of Apache Iceberg as the data lake table format to further improve pipeline SLA and costs, and improve performance.
  • Seamless schema evolution: Schema changes still require some manual effort from pipeline owners, including manually restarting Flink pipelines. In Hugo, we aim to make schema evolution a zero-touch experience by automatically detecting changes, validating compatibility, and updating tables without disruption.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Enhancing Flink Deployment with Shadow Testing

Post Syndicated from Grab Tech original https://engineering.grab.com/enchancing-flink-shadow-testing

Introduction

Ensuring the reliability of Apache Flink deployments in Grab is crucial for the availability of our business-critical, real-time applications. While all applications are tested in a staging environment before getting promoted to the production environment, there is still a class of issues that can only surface when deploying in the production environment, e.g.:

  • The new version of the application is unable to cope with the volume or the nature of production traffic.
  • The new version of the application is unable to resume from a production checkpoint or savepoint taken by the previous version of the application.
  • Certain environment-specific dependencies or configurations are malfunctioning or misconfigured.

When an application faces such issues upon deployment in production, our in-house deployment system automatically rolls it back after 10 minutes of observation, leading to a downtime of the application for about the same duration.

In this article, we will describe how Grab’s data streaming team (Coban) has enriched the traditional deployment pipeline for Flink applications with a Shadow Testing stage that eliminates this downtime during deployment failures, enhancing the availability of our Flink applications during this critical moment of their lifecycle.

Shadow Testing is a testing technique whereby a new version of an application (Shadow) is deployed in parallel with the current version of the application (Main), but without impacting it. It involves replicating production data to the new version of the application and comparing its behavior with the current version of the application to identify potential issues and regressions.

Architecture overview

Figure 1. Overall architecture of Shadow Testing.

We integrated Shadow Testing directly into the production environment, alongside the Main application (1). The Shadow application is deployed next to it via the same deployment process (2). An environment variable isShadow=true as well as a distinct jobID are injected for runtime differentiation, enabling the Shadow application to produce its results to distinct, isolated sinks that do not interfere with those of the Main application (3).

Deployment flow

Shadow Testing is embedded within our normal Flink deployment pipeline to make it a seamless experience for the users of our platform.

Figure 2. Deployment flow diagram.

The deployment flow is as follows.

  1. A user triggers a deployment of their Flink application in Grab’s in-house deployment tool. At this step, they decide whether they want to enable Shadow Testing for this particular deployment.
  2. The deployment pipeline validates the input parameters provided by the user.
  3. If the user has not opted for Shadow Testing, the deployment flow directly jumps to step 8 and deploys the latest version to the Main application. However, if the user has enabled Shadow Testing, the deployment flow first goes through the Shadow Testing stages described in steps 4 to 7.
  4. The Shadow Kubernetes manifest is baked with its set of distinctive parameters:
    • The application name is prefixed with shadow- which propagates to all the Kubernetes objects that are part of the Shadow application
    • An environment variable isShadow is injected and set to true. It instructs the Shadow application to produce its results to the shadow sinks.
    • A distinct Job ID is attributed
    • The target Kubernetes namespace is overridden with a shadow namespace
  5. The Shadow application is deployed into the shadow Kubernetes namespace.
  6. The Shadow application runs for a configured period of 1 hour by default to reach a steady state. The status of the job manager is monitored to determine the success of the Shadow Testing. If the Shadow application is stable, the Shadow Testing is considered successful.
  7. The user is prompted to continue with the deployment of the Main application.
  8. The Kubernetes manifest of the Main application is baked with its standard parameters and the environment variable isShadow is set to false.
  9. The Main application is deployed in its standard Kubernetes namespace.
  10. After 10 minutes of observation, the deployment pipeline determines if the Main application is healthy by querying the status of its job manager. If it is healthy, the Main application is considered successfully deployed. Otherwise, the deployment pipeline automatically triggers a rollback to the previous version.

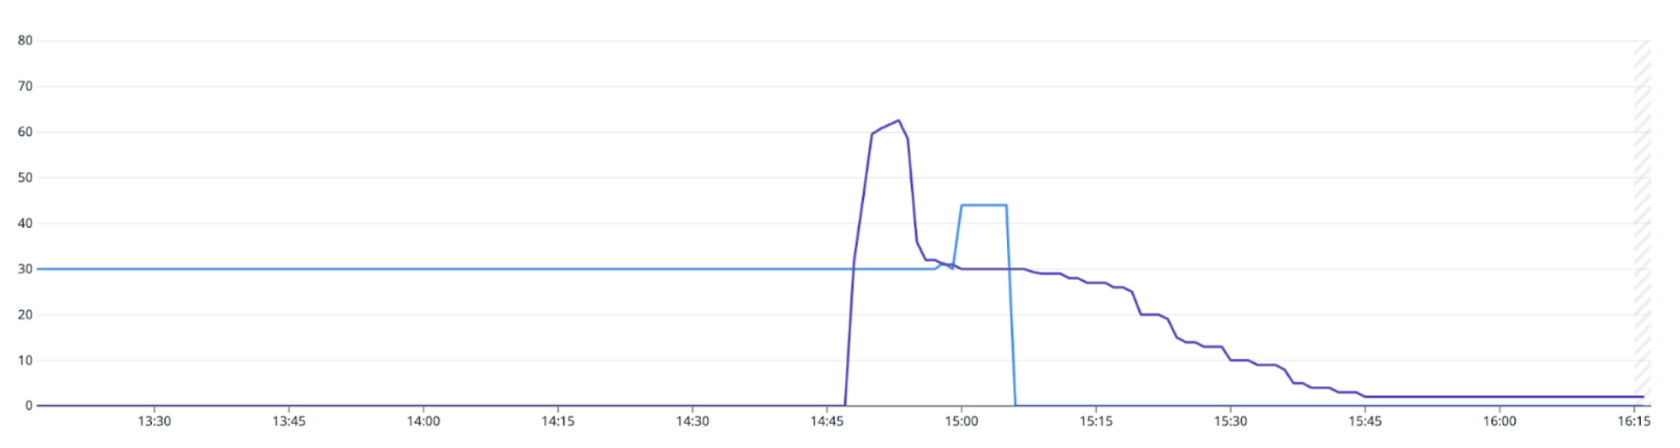
During the deployment, the user can leverage our standard observability stack to monitor the behavior of the Shadow application. For example, in the case of an Apache Kafka sink, they can compare the number of messages produced by the Main and Shadow applications.

Figure 3. Tracking of the Kafka messages.in_rate metric for the respective Kafka sink topics of the Main application (purple) and Shadow application (blue) at the beginning of the Shadow deployment stage.

Besides, our standard Datadog dashboard that comes with each application can conveniently be toggled to view the metrics of the respective Shadow application.

Connector implementation

Our standard sink and source connectors, provided by our platform, ensure the absence of interference with the Main application during Shadow Testing. For example, Kafka source connectors use distinct consumer group IDs, while the various sink connectors direct the data to dedicated shadow sinks.

The Flink application evaluates the isShadow environment variable to set up the connectors at runtime.

if (isShadow){
    // Shadow Testing operation
}
else {
    // Normal operation
}

The following table shows how some typical connectors are dynamically configured if isShadow=true:

Type Connector Dynamic configuration
Source Kafka The consumer group ID for the Shadow application is suffixed with -shadow. This is crucial so as to consume a full copy of the data stream without interfering with the Main application.
Main application: consumerGroup = <application_name>
Shadow application: consumerGroup = <application_name>-shadow
Source Change Data Capture The Server ID range of Debezium is shifted to the next non-overlapping range of the same size. This enables the Shadow application to get a full copy of the database binlog stream without interfering with the Main application. Note that the misleading Server ID naming is because Debezium acts as a pseudo-replica of the database server.
Main application: serverId = 1001-2000
Shadow application: serverId = 2001 – 3000
Sink Kafka The cluster endpoint is replaced with that of a Kafka cluster dedicated to Shadow Testing, set up with auto.create.topics.enable=true and 8h retention.
Main application: brokers = <flink-kafka>:9092
Shadow application: brokers = <flink-kafka-shadow>:9092
Sink S3 The S3 bucket name is replaced with that of a bucket dedicated to Shadow Testing, set up with a 7-day retention lifecycle policy.
Main application: s3://<flink-s3>/<application_name>
Shadow application: s3://<flink-s3-shadow>/<application_name>
Sink Metrics The StatsD prefix configuration is overridden. A shadow. prefix is added.
Main application: flink.<application_name>.<metric_name>
Shadow application: shadow.flink.<application_name>.<metric_name>
Sink Logs The Shadow Kubernetes manifest prefixes the Shadow application name with shadow-. The resulting name becomes available as a field in Kibana, enabling discriminated filtering. This tweak is done at the Kubernetes manifest level, not at the Flink application level.
Main application: app_name = <application_name>
Shadow application: app_name = shadow-<application_name>

Conclusion

Our Shadow Testing framework represents a meaningful step forward in enhancing the reliability of our Flink applications during deployment. By leveraging and enriching the existing components of our platform, we have created a robust system that enables our users to confidently increase their Deployment Frequency and reduce their Change Failure Rate.

What’s next

To drive wider adoption, we intend to support more source and sink connectors. By expanding the range of supported connectors, we could empower teams to leverage Shadow Testing across a broader spectrum of applications.

For connectors that are less frequently used, we consider implementing a no-op approach combined with metrics collection to expose a minimal set of actionable data points.

We will remain focused on making Shadow Testing accessible, scalable, and adaptable to various applications. Stay tuned as we continue to push the boundaries of innovation and deliver solutions that enhance reliability and efficiency across our systems.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Data Mesh at Grab Part II: The Foundational Tools behind Certification

Post Syndicated from Grab Tech original https://engineering.grab.com/data-mesh-2

Introduction

In Part I, we discussed why Grab is investing in a data mesh, referred to as the Signals Marketplace within Grab, as part of our evolving data culture. We also explained how data certification aids teams in reliably reusing data across different domains. However, cultural change doesn’t occur through principles alone; it happens when tools reshape people’s daily behaviors. Therefore, it is crucial for us to develop effective platforms that integrate these practices.

This follow-up focuses on these platforms that make certification work at Grab:

  • Hubble – the central metadata management platform with a built-in certification engine.
  • Genchi – the data quality observability platform.
  • Data Contract Registry – the central service for managing data contracts.

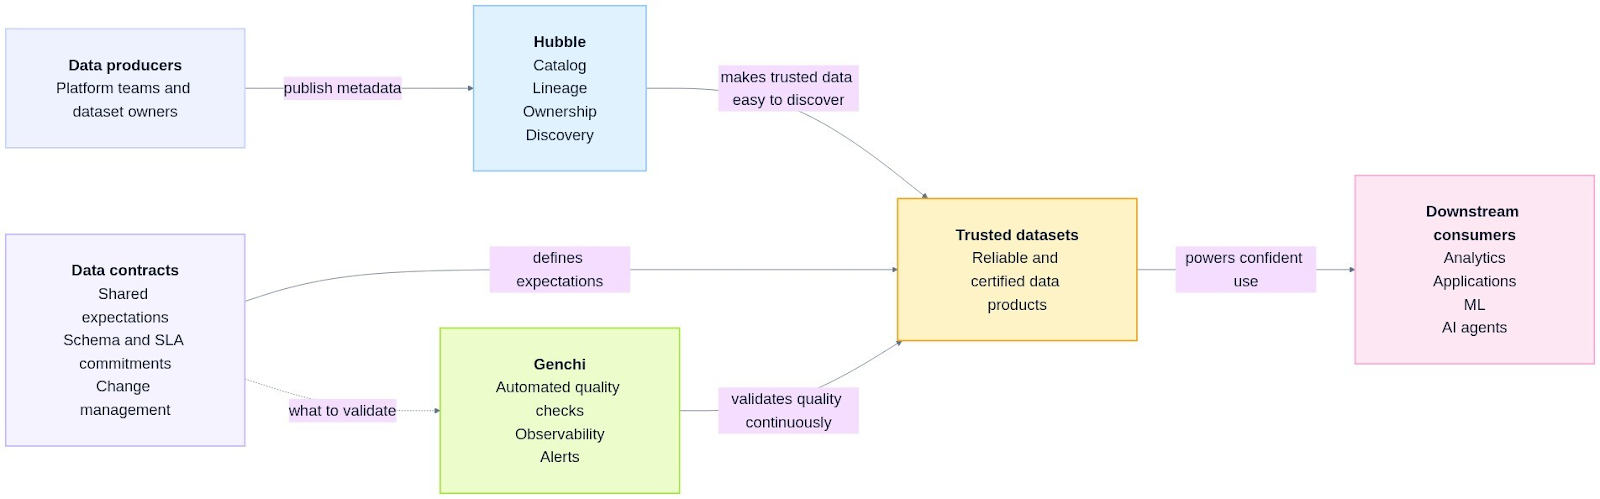
Together, these platforms turn data mesh principles into an operational system that scales across hundreds of thousands of datasets, streams, attributes, and metrics.

Hubble: The data discovery and governance layer

Hubble is Grab’s central metadata management platform and data catalog for all data assets, including datasets, dashboards, metrics, Machine learning (ML) models, and more. Built on top of the open‑source DataHub and heavily extended for Grab’s needs, it is the discovery and governance layer for the Signals Marketplace.

Figure 1. Hubble cataloging data assets across various data platforms in Grab.

What Hubble does for data mesh

For certification and data mesh, Hubble provides a few key capabilities:

  • Search and discovery: Data analysts/scientists, engineers, and product managers use Hubble to search the rich swath of data assets, then inspect schemas, documentation, lineage, and usage statistics in one place. This replaces back-channel questions and tribal knowledge with a single, self-serve catalog.
  • Ownership and domains: Every asset is tied to a domain and explicit technical and business owners. This enforces the domain ownership model that Signals Marketplace depends on. Producers are clearly accountable for the quality and lifecycle of the data products they publish.
  • Data contracts and documentation: Data contracts, classifications, and rich documentation live as structured metadata attached to each asset, not scattered across wikis and slide decks. Producers and consumers share the same source of truth when they ask questions like, “what does this table guarantee?”.
  • Lineage and impact analysis: Hubble provides table, column, and metric-level lineage so owners can see which teams and pipelines depend on their data before making breaking changes or deprecations. Instead of guessing, they can answer “what will I break?” with a single click.
  • Certification status: The familiar “Hubble green tick” turns trust into a first-class signal in the catalog. Assets that meet Grab’s certification criteria are clearly marked with a drill-down view of which criteria are satisfied (ownership, documentation, contracts, quality tests, upstream certification) and which are still missing.

From a consumer’s point of view, this collapses a lot of uncertainty into a simple workflow: search → filter to “certified” → pick the most suitable asset. They don’t need to reverse-engineer reliability from table names and hearsay.

Hubble’s system architecture

The open-source DataHub architecture is fundamentally event-driven and designed for high extensibility, moving away from the “passive” catalogs of the past, towards a “living” metadata graph. DataHub models everything as an Entity (e.g., a Dataset), composed of multiple Aspects (atomic versioned metadata like SchemaMetadata or Ownership), connected by Relationships (e.g., DownstreamOf).

Since introducing DataHub as Grab’s central data catalog in 2022, we’ve tailored it to Grab’s specific needs while continuously rebasing onto the latest open-source DataHub releases. This lets us adopt new capabilities from the community quickly, contribute improvements back, and evolve Hubble without forking away from the main project.

On top of the DataHub foundation, Hubble ingests metadata from Grab’s source platforms in two ways. Source systems either push changes as they happen, or Hubble periodically pulls metadata via Airflow jobs into the central metadata service that exposes GraphQL and REST APIs. Every change is then published to Kafka as metadata events (low-level change logs for indexers and audits, and higher-level semantic events for workflows), keeping Hubble’s search and lineage indices fresh and allowing downstream integrations like certification, deprecation notices, and governance automation to react to metadata changes in near real time.

This architecture is crucial for a data mesh because metadata evolves more rapidly than organizational changes. As domains change, tables are relocated, or pipelines are refactored, Hubble continuously updates, allowing certification to keep pace without the need for manual re-audits.

Figure 2. Hubble’s system architecture.

Computational certification via the certification engine on Hubble

A data asset’s certification state is not a manual label, it is computed by an event-driven certification engine built on the DataHub Actions framework. As source platforms for tables, streams, metrics, and user attributes push metadata into Hubble, every change becomes a metadata event. The engine subscribes to these events and re-evaluates the certification state of the data asset based on the predetermined certification criteria.

Conceptually, assets move between four states:

  • Uncertified: Never met all criteria.
  • Certified: Asset itself meets all required criteria.
  • CertifiedPlus: Stricter conditions than Certified, requiring both the asset and all of its upstreams to meet the criteria.
  • Revoked: Previously certified but now out of compliance.

The state diagram below captures how assets move between these states as metadata and upstream health change.

Figure 3. Certification state diagram.

While each asset type can add its own nuances (for example, metrics and attributes may also require explicit endorsement from business data owners), the core certification criteria are consistent:

  • Ownership and domain: Clear domain assignment plus accountable technical and business data owners.
  • Documentation and semantics: Table/metric documentation and, where relevant, column-level descriptions so consumers understand what the data means.
  • Lineage and upstream trust: For stronger levels like CertifiedPlus, upstream lineage must be present, and upstream assets must themselves be certified.
  • Contracts and runtime quality: Linked data contracts that spell out expectations, backed by required Genchi tests for freshness, volume/completeness, schema stability, and critical business checks.
  • Governance signals: No conflicting deprecation flags or policy violations (for example, missing required classifications on sensitive data).

If an asset satisfies the base criteria, the engine writes a certification aspect back into Hubble and surfaces it as a green tick; if the asset later falls out of compliance, certification is revoked, and downstream assets are re-evaluated as needed. This is because all certification changes are stored as time-series metadata and driven by events rather than a one-off checklist; certification becomes a continuous, metadata-driven process that keeps pace as the entity evolves.

Genchi: The data quality observability layer

Genchi is Grab’s in-house, self-service data quality observability platform. It allows teams to define and run data quality tests on their datasets, receive alerts when something goes wrong, and integrate those tests directly into data contracts so that issues are caught and contained before they impact downstream consumers.

Figure 4. Genchi job configuration page, where dataset owners enroll a table and set up freshness, volume, schema, and other data quality tests for it.

What Genchi does for data mesh

In a data mesh, every domain is responsible for the quality of the data products it publishes. Genchi is the guardrail that makes that responsibility practical at scale. At its core, Genchi turns “good data” into clear, testable pillars that a data asset must satisfy:

  • Freshness and timeliness: Is the data recent enough to trust? Genchi runs data freshness and pipeline-freshness checks so owners know when today’s numbers are really “today’s” and can spot delayed loads before they hit dashboards or models.
  • Completeness and volume: Are we seeing all the records we expect? Volume and completeness tests compare current loads against historical baselines or source systems to flag partial backfills, silent drops, or suspicious spikes.
  • Structural stability (schema): Did the shape of the data change? Schema checks detect added/removed columns and type changes so that teams don’t discover breaking changes only after pipelines or reports start failing.
  • Semantic validity (values and business rules): Do the values themselves make sense? Column-level and X-Validation tests enforce constraints like uniqueness, ranges, patterns, cross-table reconciliations, and more advanced anomaly detection on row counts and null percentages.

Wrapped around these pillars is the operational layer:

  • Genchi runs these checks continuously (on schedule or on pipeline completion), emits real-time alerts, and helps teams drill into failing records and trends instead of debugging blind.
  • Its health signals flow into the catalog and incident tooling, so consumers see quality status alongside metadata and contract breaches are handled consistently.

The result is a mesh where domains publish data products with explicit, machine-enforced quality guarantees, and consumers can safely reuse them without a central team hand-holding every request.

Genchi’s system architecture

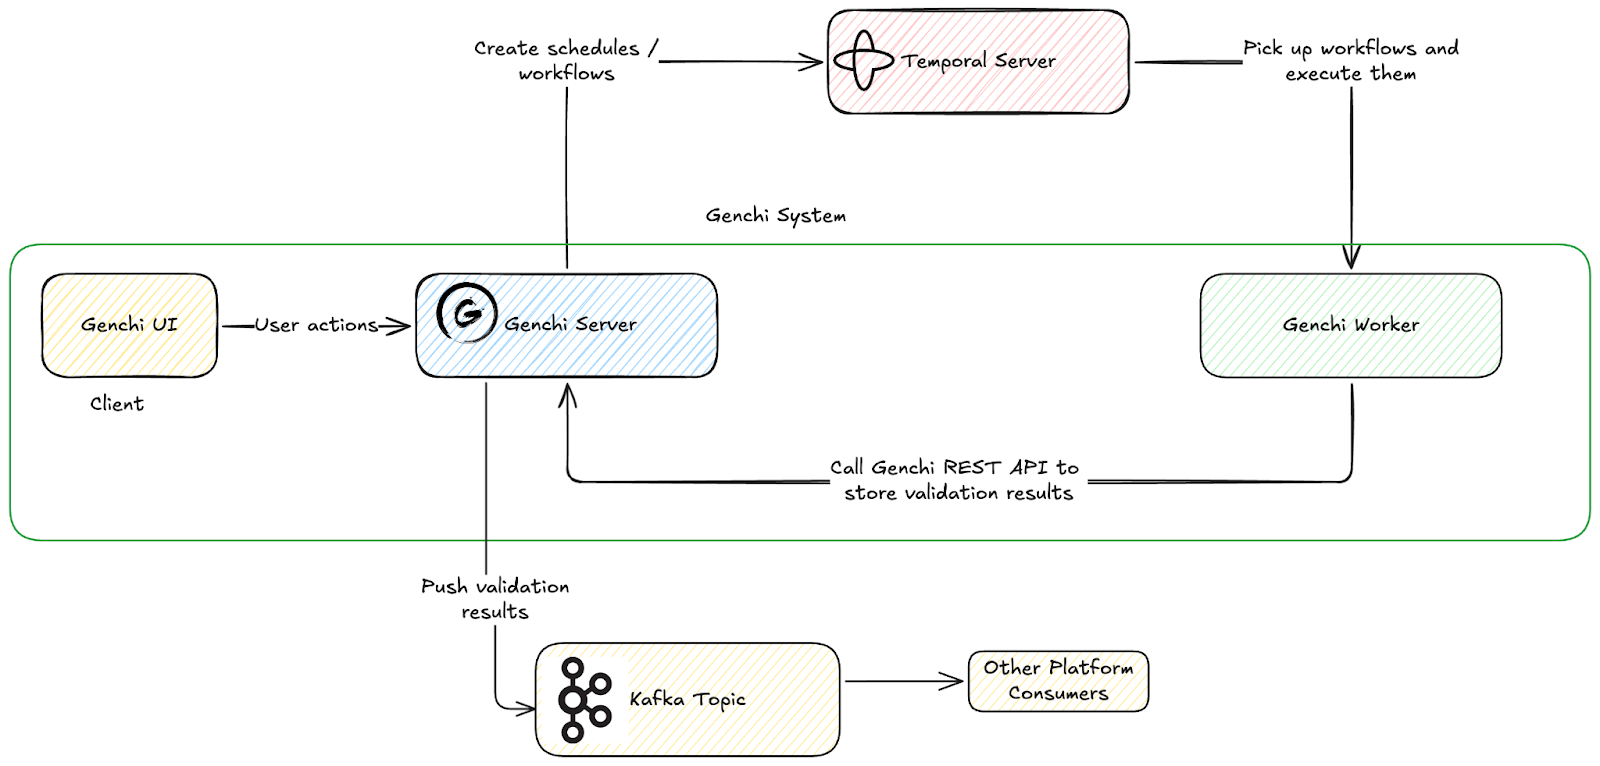
The Genchi system is designed to handle validation workflows triggered by user actions or automated schedules. It utilizes Temporal for reliable workflow orchestration and Kafka for event-driven data distribution to downstream consumers.

Figure 5. Genchi’s system architecture.

Triggering tests on pipeline completion with Sync with Pipeline (SWP)

Before SWP, Genchi tests lived on their own cron schedules, completely decoupled from the Airflow pipelines that actually produced the data. Teams had to manually copy pipeline crons into Genchi, juggle offset/lookback math to point at the “right” pipeline batch, and hope that nothing drifted over time. The result: misconfigured pipeline duration Service Level Agreement (SLA) checks, and tests sometimes running too early, too late, or against the wrong batch. This leads to noisy alerts and false-positive Data Production Issue (DPI).

To solve this, Genchi leans on Lighthouse, Grab’s pipeline execution and monitoring service. Lighthouse tracks when Airflow jobs start, finish, and which data interval they cover, and exposes that as structured execution events that the rest of the observability stack can consume.

SWP then flips Genchi from “best-effort cron alignment” to event-driven orchestration. Instead of guessing when a pipeline should have finished, Genchi listens to Lighthouse execution events. When a pipeline run is completed, Lighthouse emits an event with the run’s schedule and data interval; Genchi consumes that event, spins up an ad-hoc validation run aligned to that execution, and runs data-quality tests on the corresponding slice of data.

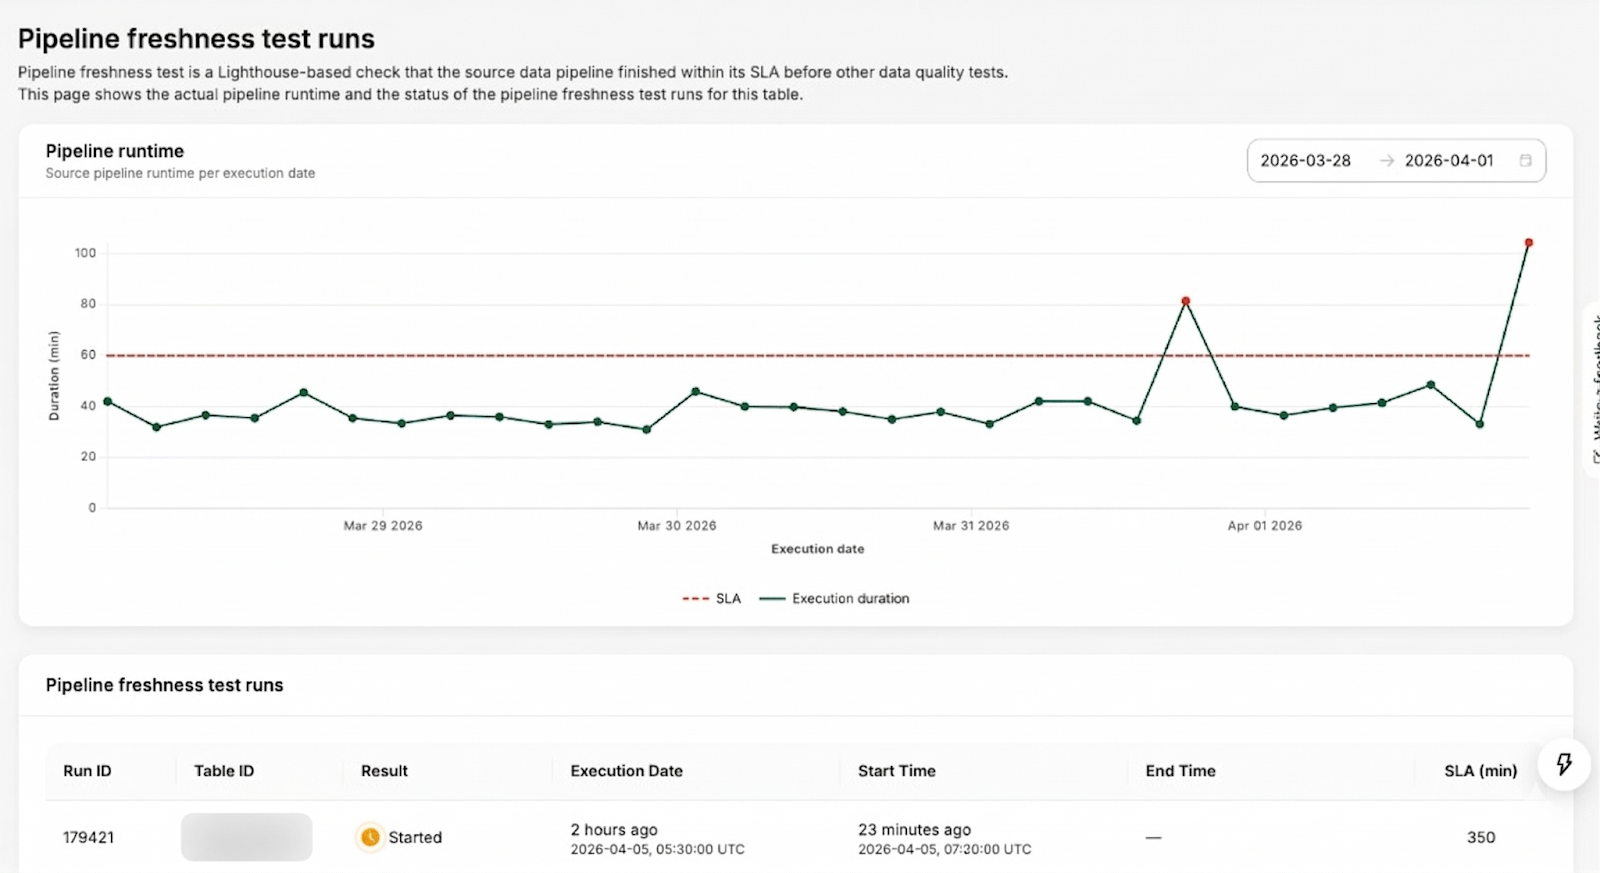
Pipeline-freshness is modeled as its own run type, separate from the data-quality tests that run on pipeline completion. Instead of inspecting rows, it is triggered asynchronously on the same schedule as the pipeline and tracks when each run actually completes in Lighthouse. This gives data producers an intuitive way to get alerted when a pipeline exceeds its expected runtime, and to review historical runtime behavior for any drift over time.

In practice, this makes test orchestration both simpler and more trustworthy. Users no longer need to think about crons or offsets for their data validation jobs. “Run after my pipeline finishes” becomes the default, with advanced overrides for custom schedules when needed. Misconfigured freshness tests and noisy DPIs drop, because Genchi is now anchored to real pipeline execution signals rather than approximations.

Figure 6. Genchi pipeline-freshness run page for a table, showing the historical runtime patterns and the SLA status.

Data Contract Registry: The producer–consumer agreement layer

At Grab, a data contract is the explicit, versioned agreement between a producer and its consumers that defines the data’s shape and semantics, the quality and availability guarantees around it, and the rules for how and for how long it may be used. The Data Contract Registry is the source of truth for these agreements, while Genchi and platform-specific observability stacks continuously verify that reality still matches what the contract promises.

What Data Contract Registry does for data mesh

Within Grab’s data mesh, the Data Contract Registry is the producer–consumer agreement layer: it centralizes contracts for key assets (data lake tables, Kafka streams, metrics) so expectations on shape, quality, SLAs, and lifecycle live in one canonical place instead of being scattered across individual platforms. That single source of truth underpins Hubble certification (only assets with valid contracts can be certified), gives Kinabalu (Grab’s central incident lifecycle orchestrator) the context it needs to open and route DPIs when checks fail, and lets Ouroboros (a table lifecycle management tool) interpret lifecycle clauses consistently.

This is important for a data mesh because it transforms the concept of “data as a product” from a mere slogan into an operational reality. Contracts provide domain teams with a clear and enforceable method to specify their guarantees, offering consumers a solid foundation for trust and data reuse across domains. Importantly, a contract is only valuable if its promises are verifiable and enforceable. Schema expectations, quality checks, and SLAs are all connected to concrete tests and health endpoints, enabling downstream platforms to automatically detect breaches and manage or mitigate breaking changes, rather than treating the contract as static documentation.

On top of storing contracts, the registry also manages contract changes. When a contract evolves, say a schema tweak, a new freshness SLA, or a planned deprecation, it identifies the right stakeholders (direct downstream owners, heavy query users, and, for critical assets, deeper dependencies) and pushes targeted Slack notifications. Producers get a structured way to roll out changes safely while consumers get timely, actionable signals instead of surprise breakages so that both enforcement and change management are baked into the mesh.

In addition to storing contracts, the registry also manages contract changes. When a contract evolves such as a schema adjustment, a new freshness SLA, or a planned deprecation, it identifies the appropriate stakeholder (direct downstream owners, heavy query users, and critical assets with deeper dependencies) and then sends targeted Slack notifications to these stakeholders. This process provides producers with a structured method to implement changes safely, while consumers receive timely and actionable alerts, preventing unexpected disruptions. As a result, both enforcement and change management are seamlessly integrated into the data mesh.

The data contract specification

Under the hood, a data contract in the registry is a JSON construct that follows the contract specification. Grab’s data contract specification is inspired by the public Data Contract Specification, but adapted to our environment so that contracts plug directly into our observability stack and automated incident management workflows.

Notably, we embed data health and test health URLs in the contract itself. Each data-quality rule points to a concrete health endpoint, so Kinabalu can determine contract breaches and create DPIs by calling those test health URLs, without hard-coding what “healthy” means. For example, a completeness test on the latest partition can be marked healthy only if the last N days are complete, not just because the most recent test run happened to pass. The data health URL at the contract root then lets Kinabalu fetch the overall diagnosis and decide who the DPI should be assigned to. More on this will be covered in Part III.

Here’s a simplified example of a contract for a data-lake table:

{
  "specification_version": 1,
  "asset_urn": "urn:li:dataset:(urn:li:dataPlatform:hive,genchi.validation_jobs,PROD)",
  "entity_type": "datalake_table",
  "health_url": "https://example-hugo.grab.com/assets/genchi.validation_jobs/health",
  "contract_details": {
    "contact": {
      "oncall_group": "oncall-genchi",
      "slack_channel": "ask-genchi"
    },
    "terms": {
      "usage": "Source of truth for all genchi validation jobs.",
      "limitations": "Not suitable for real-time use cases.",
      "notice_period_in_days": 14
    },
    "schema": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_schema_test/health",
        "uid": "fundamental_schema_test",
        "version": 1
      }

    ],
    "sla": {
      "freshness": [
        {
          "type": "genchi",
          "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_freshness_test/health",
          "uid": "fundamental_freshness_test",
          "version": 1
        }
      ],
      "lifecycle": null
    },
    "data_quality": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_completeness_test/health",
        "uid": "fundamental_completeness_test",
        "version": 1
      }
    ]
  }
}

The contract in the registry only stores references to enforceable rules, which are an identifier and version, like the example above, rather than the full configuration body. This keeps contracts lightweight and tool-agnostic, while giving rule-enforcement tools (Genchi for data-quality tests, Ouroboros for table lifecycle) and Kinabalu a stable handle to resolve the actual rule definition in their own systems, without duplicating configuration or letting it drift across platforms.

Conclusion

By bringing Hubble, Genchi, and the Data Contract Registry together, we provide the foundational tools to build trust in certified data assets. Hubble enables discovery and establishes domains and ownership; the Data Contract Registry captures explicit expectations between producers and consumers; and Genchi continuously validates those promises with tests on freshness, volume, schema, and business rules. Hubble’s certification engine then evaluates these ownership, contract, and quality signals to decide whether an asset meets Grab’s standards and surfaces that as a visible certification state. As a result, consumers can confidently default to certified assets, usage converges on a smaller, better-governed pool of datasets, and certification becomes a mechanism that changes producer behavior and guides consumer choice. We saw this convergence in practice. In just one year since the Signals Marketplace campaign began in 2024, the number of P80 datasets (the most used tables that account for 80% of all queries) has dropped by over 58%.

This data foundation is especially important in an AI-first future for Grab. Certified streams, tables, metrics, and attributes give AI agents and automated analytics a default substrate they can rely on. With Hubble and Genchi, data producers have clear ownership, contracts, and observability. Data consumers can discover and trust certified assets without guesswork, and platform teams can measure and improve Signals Marketplace health over time (for example, queries on certified assets, lineage depth, and cost). Together, these capabilities turn “data mesh” from a slogan into an operational, AI-ready marketplace of reliable, reusable signals that power decisions across Grab.

Figure 7. Building trust in certified data assets through discovery, contracts, and continuous validation.

What’s next

In the next blog, we’ll zoom into the DPI process itself with Kinabalu as the incident lifecycle orchestrator:

  • How Genchi test failures and data contract breaches turn into DPIs.
  • How DPI is assigned based on root causes and what sets the priority level.
  • The patterns we’ve seen in “noisy” vs actionable DPIs, and what we’ve changed in our platforms.
  • How we’re using automation and agents to reduce DPI toil and close the loop back into certification.

We’ll walk through concrete case studies showing how a single broken table moves from first failure, to diagnosis and fix, to updated contracts and a more resilient certified data asset.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
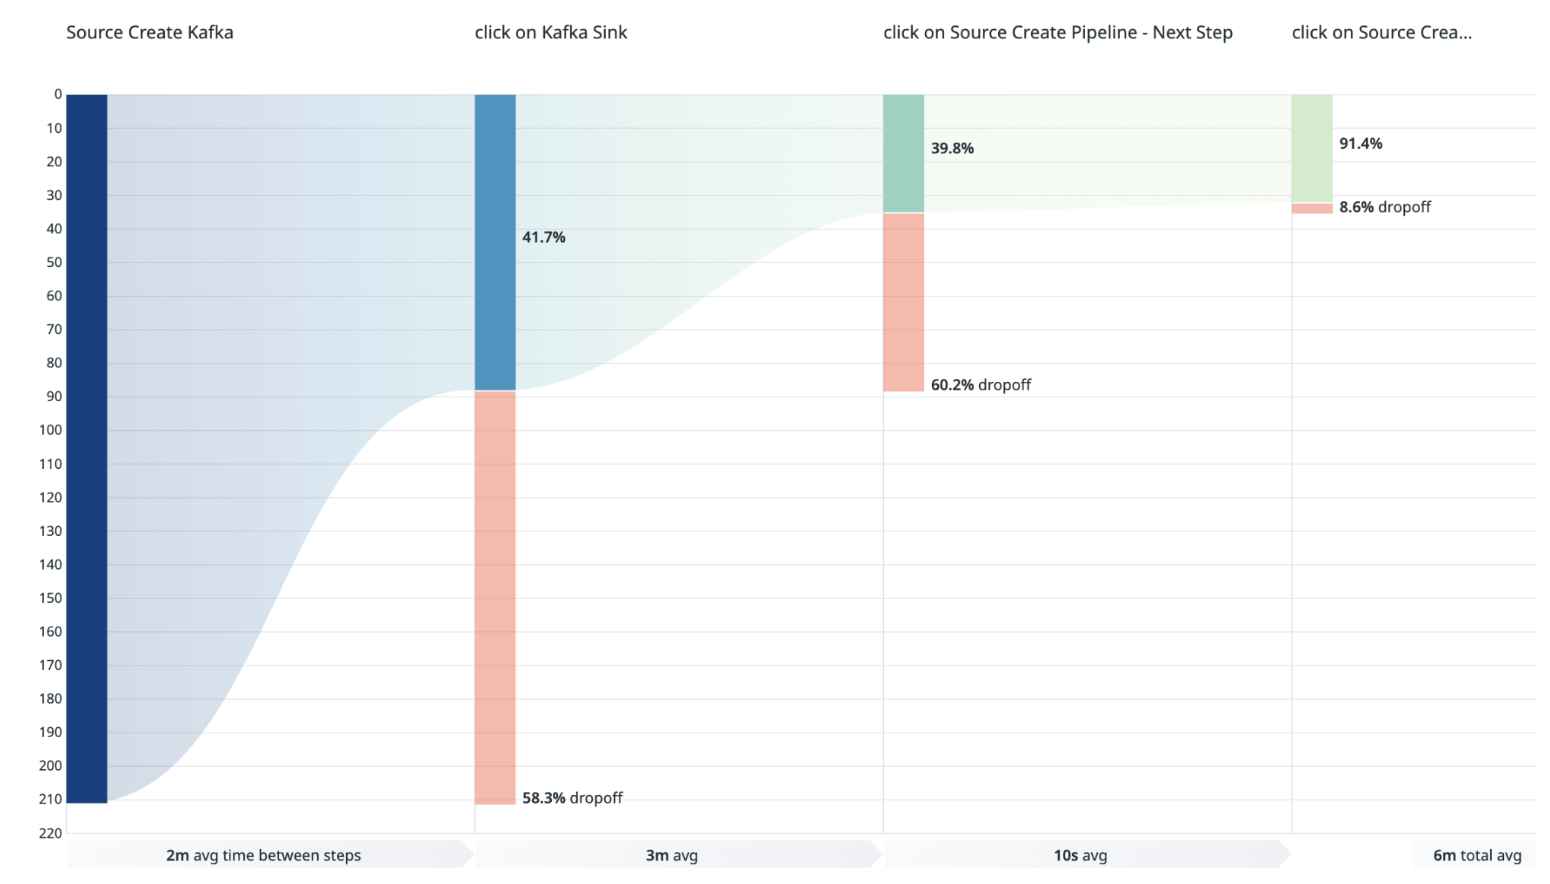
Data Mesh at Grab Part II: The Foundational Tools behind Certification

Post Syndicated from Grab Tech original https://engineering.grab.com/data-mesh-part-2-the-foundational-tools-behind-certification

Introduction

In Part I, we discussed why Grab is investing in a data mesh, referred to as the Signals Marketplace within Grab, as part of our evolving data culture. We also explained how data certification aids teams in reliably reusing data across different domains. However, cultural change doesn’t occur through principles alone; it happens when tools reshape people’s daily behaviors. Therefore, it is crucial for us to develop effective platforms that integrate these practices.

This follow-up focuses on these platforms that make certification work at Grab:

  • Hubble – the central metadata management platform with a built-in certification engine.
  • Genchi – the data quality observability platform.
  • Data Contract Registry – the central service for managing data contracts.

Together, these platforms turn data mesh principles into an operational system that scales across hundreds of thousands of datasets, streams, attributes, and metrics.

Hubble: The data discovery and governance layer

Hubble is Grab’s central metadata management platform and data catalog for all data assets, including datasets, dashboards, metrics, Machine learning (ML) models, and more. Built on top of the open‑source DataHub and heavily extended for Grab’s needs, it is the discovery and governance layer for the Signals Marketplace.

Figure 1. Hubble cataloging data assets across various data platforms in Grab.

What Hubble does for data mesh

For certification and data mesh, Hubble provides a few key capabilities:

  • Search and discovery: Data analysts/scientists, engineers, and product managers use Hubble to search the rich swath of data assets, then inspect schemas, documentation, lineage, and usage statistics in one place. This replaces back-channel questions and tribal knowledge with a single, self-serve catalog.
  • Ownership and domains: Every asset is tied to a domain and explicit technical and business owners. This enforces the domain ownership model that Signals Marketplace depends on. Producers are clearly accountable for the quality and lifecycle of the data products they publish.
  • Data contracts and documentation: Data contracts, classifications, and rich documentation live as structured metadata attached to each asset, not scattered across wikis and slide decks. Producers and consumers share the same source of truth when they ask questions like, “what does this table guarantee?”.
  • Lineage and impact analysis: Hubble provides table, column, and metric-level lineage so owners can see which teams and pipelines depend on their data before making breaking changes or deprecations. Instead of guessing, they can answer “what will I break?” with a single click.
  • Certification status: The familiar “Hubble green tick” turns trust into a first-class signal in the catalog. Assets that meet Grab’s certification criteria are clearly marked with a drill-down view of which criteria are satisfied (ownership, documentation, contracts, quality tests, upstream certification) and which are still missing.

From a consumer’s point of view, this collapses a lot of uncertainty into a simple workflow: search → filter to “certified” → pick the most suitable asset. They don’t need to reverse-engineer reliability from table names and hearsay.

Hubble’s system architecture

The open-source DataHub architecture is fundamentally event-driven and designed for high extensibility, moving away from the “passive” catalogs of the past, towards a “living” metadata graph. DataHub models everything as an Entity (e.g., a Dataset), composed of multiple Aspects (atomic versioned metadata like SchemaMetadata or Ownership), connected by Relationships (e.g., DownstreamOf).

Since introducing DataHub as Grab’s central data catalog in 2022, we’ve tailored it to Grab’s specific needs while continuously rebasing onto the latest open-source DataHub releases. This lets us adopt new capabilities from the community quickly, contribute improvements back, and evolve Hubble without forking away from the main project.

On top of the DataHub foundation, Hubble ingests metadata from Grab’s source platforms in two ways. Source systems either push changes as they happen, or Hubble periodically pulls metadata via Airflow jobs into the central metadata service that exposes GraphQL and REST APIs. Every change is then published to Kafka as metadata events (low-level change logs for indexers and audits, and higher-level semantic events for workflows), keeping Hubble’s search and lineage indices fresh and allowing downstream integrations like certification, deprecation notices, and governance automation to react to metadata changes in near real time.

This architecture is crucial for a data mesh because metadata evolves more rapidly than organizational changes. As domains change, tables are relocated, or pipelines are refactored, Hubble continuously updates, allowing certification to keep pace without the need for manual re-audits.

Figure 2. Hubble’s system architecture.

Computational certification via the certification engine on Hubble

A data asset’s certification state is not a manual label, it is computed by an event-driven certification engine built on the DataHub Actions framework. As source platforms for tables, streams, metrics, and user attributes push metadata into Hubble, every change becomes a metadata event. The engine subscribes to these events and re-evaluates the certification state of the data asset based on the predetermined certification criteria.

Conceptually, assets move between four states:

  • Uncertified: Never met all criteria.
  • Certified: Asset itself meets all required criteria.
  • CertifiedPlus: Stricter conditions than Certified, requiring both the asset and all of its upstreams to meet the criteria.
  • Revoked: Previously certified but now out of compliance.

The state diagram below captures how assets move between these states as metadata and upstream health change.

Figure 3. Certification state diagram.

While each asset type can add its own nuances (for example, metrics and attributes may also require explicit endorsement from business data owners), the core certification criteria are consistent:

  • Ownership and domain: Clear domain assignment plus accountable technical and business data owners.
  • Documentation and semantics: Table/metric documentation and, where relevant, column-level descriptions so consumers understand what the data means.
  • Lineage and upstream trust: For stronger levels like CertifiedPlus, upstream lineage must be present, and upstream assets must themselves be certified.
  • Contracts and runtime quality: Linked data contracts that spell out expectations, backed by required Genchi tests for freshness, volume/completeness, schema stability, and critical business checks.
  • Governance signals: No conflicting deprecation flags or policy violations (for example, missing required classifications on sensitive data).

If an asset satisfies the base criteria, the engine writes a certification aspect back into Hubble and surfaces it as a green tick; if the asset later falls out of compliance, certification is revoked, and downstream assets are re-evaluated as needed. This is because all certification changes are stored as time-series metadata and driven by events rather than a one-off checklist; certification becomes a continuous, metadata-driven process that keeps pace as the entity evolves.

Genchi: The data quality observability layer

Genchi is Grab’s in-house, self-service data quality observability platform. It allows teams to define and run data quality tests on their datasets, receive alerts when something goes wrong, and integrate those tests directly into data contracts so that issues are caught and contained before they impact downstream consumers.

Figure 4. Genchi job configuration page, where dataset owners enroll a table and set up freshness, volume, schema, and other data quality tests for it.

What Genchi does for data mesh

In a data mesh, every domain is responsible for the quality of the data products it publishes. Genchi is the guardrail that makes that responsibility practical at scale. At its core, Genchi turns “good data” into clear, testable pillars that a data asset must satisfy:

  • Freshness and timeliness: Is the data recent enough to trust? Genchi runs data freshness and pipeline-freshness checks so owners know when today’s numbers are really “today’s” and can spot delayed loads before they hit dashboards or models.
  • Completeness and volume: Are we seeing all the records we expect? Volume and completeness tests compare current loads against historical baselines or source systems to flag partial backfills, silent drops, or suspicious spikes.
  • Structural stability (schema): Did the shape of the data change? Schema checks detect added/removed columns and type changes so that teams don’t discover breaking changes only after pipelines or reports start failing.
  • Semantic validity (values and business rules): Do the values themselves make sense? Column-level and X-Validation tests enforce constraints like uniqueness, ranges, patterns, cross-table reconciliations, and more advanced anomaly detection on row counts and null percentages.

Wrapped around these pillars is the operational layer:

  • Genchi runs these checks continuously (on schedule or on pipeline completion), emits real-time alerts, and helps teams drill into failing records and trends instead of debugging blind.
  • Its health signals flow into the catalog and incident tooling, so consumers see quality status alongside metadata and contract breaches are handled consistently.

The result is a mesh where domains publish data products with explicit, machine-enforced quality guarantees, and consumers can safely reuse them without a central team hand-holding every request.

Genchi’s system architecture

The Genchi system is designed to handle validation workflows triggered by user actions or automated schedules. It utilizes Temporal for reliable workflow orchestration and Kafka for event-driven data distribution to downstream consumers.

Figure 5. Genchi’s system architecture.

Triggering tests on pipeline completion with Sync with Pipeline (SWP)

Before SWP, Genchi tests lived on their own cron schedules, completely decoupled from the Airflow pipelines that actually produced the data. Teams had to manually copy pipeline crons into Genchi, juggle offset/lookback math to point at the “right” pipeline batch, and hope that nothing drifted over time. The result: misconfigured pipeline duration Service Level Agreement (SLA) checks, and tests sometimes running too early, too late, or against the wrong batch. This leads to noisy alerts and false-positive Data Production Issue (DPI).

To solve this, Genchi leans on Lighthouse, Grab’s pipeline execution and monitoring service. Lighthouse tracks when Airflow jobs start, finish, and which data interval they cover, and exposes that as structured execution events that the rest of the observability stack can consume.

SWP then flips Genchi from “best-effort cron alignment” to event-driven orchestration. Instead of guessing when a pipeline should have finished, Genchi listens to Lighthouse execution events. When a pipeline run is completed, Lighthouse emits an event with the run’s schedule and data interval; Genchi consumes that event, spins up an ad-hoc validation run aligned to that execution, and runs data-quality tests on the corresponding slice of data.

Pipeline-freshness is modeled as its own run type, separate from the data-quality tests that run on pipeline completion. Instead of inspecting rows, it is triggered asynchronously on the same schedule as the pipeline and tracks when each run actually completes in Lighthouse. This gives data producers an intuitive way to get alerted when a pipeline exceeds its expected runtime, and to review historical runtime behavior for any drift over time.

In practice, this makes test orchestration both simpler and more trustworthy. Users no longer need to think about crons or offsets for their data validation jobs. “Run after my pipeline finishes” becomes the default, with advanced overrides for custom schedules when needed. Misconfigured freshness tests and noisy DPIs drop, because Genchi is now anchored to real pipeline execution signals rather than approximations.

Figure 6. Genchi pipeline-freshness run page for a table, showing the historical runtime patterns and the SLA status.

Data Contract Registry: The producer–consumer agreement layer

At Grab, a data contract is the explicit, versioned agreement between a producer and its consumers that defines the data’s shape and semantics, the quality and availability guarantees around it, and the rules for how and for how long it may be used. The Data Contract Registry is the source of truth for these agreements, while Genchi and platform-specific observability stacks continuously verify that reality still matches what the contract promises.

What Data Contract Registry does for data mesh

Within Grab’s data mesh, the Data Contract Registry is the producer–consumer agreement layer: it centralizes contracts for key assets (data lake tables, Kafka streams, metrics) so expectations on shape, quality, SLAs, and lifecycle live in one canonical place instead of being scattered across individual platforms. That single source of truth underpins Hubble certification (only assets with valid contracts can be certified), gives Kinabalu (Grab’s central incident lifecycle orchestrator) the context it needs to open and route DPIs when checks fail, and lets Ouroboros (a table lifecycle management tool) interpret lifecycle clauses consistently.

This is important for a data mesh because it transforms the concept of “data as a product” from a mere slogan into an operational reality. Contracts provide domain teams with a clear and enforceable method to specify their guarantees, offering consumers a solid foundation for trust and data reuse across domains. Importantly, a contract is only valuable if its promises are verifiable and enforceable. Schema expectations, quality checks, and SLAs are all connected to concrete tests and health endpoints, enabling downstream platforms to automatically detect breaches and manage or mitigate breaking changes, rather than treating the contract as static documentation.

On top of storing contracts, the registry also manages contract changes. When a contract evolves, say a schema tweak, a new freshness SLA, or a planned deprecation, it identifies the right stakeholders (direct downstream owners, heavy query users, and, for critical assets, deeper dependencies) and pushes targeted Slack notifications. Producers get a structured way to roll out changes safely while consumers get timely, actionable signals instead of surprise breakages so that both enforcement and change management are baked into the mesh.

In addition to storing contracts, the registry also manages contract changes. When a contract evolves such as a schema adjustment, a new freshness SLA, or a planned deprecation, it identifies the appropriate stakeholder (direct downstream owners, heavy query users, and critical assets with deeper dependencies) and then sends targeted Slack notifications to these stakeholders. This process provides producers with a structured method to implement changes safely, while consumers receive timely and actionable alerts, preventing unexpected disruptions. As a result, both enforcement and change management are seamlessly integrated into the data mesh.

The data contract specification

Under the hood, a data contract in the registry is a JSON construct that follows the contract specification. Grab’s data contract specification is inspired by the public Data Contract Specification, but adapted to our environment so that contracts plug directly into our observability stack and automated incident management workflows.

Notably, we embed data health and test health URLs in the contract itself. Each data-quality rule points to a concrete health endpoint, so Kinabalu can determine contract breaches and create DPIs by calling those test health URLs, without hard-coding what “healthy” means. For example, a completeness test on the latest partition can be marked healthy only if the last N days are complete, not just because the most recent test run happened to pass. The data health URL at the contract root then lets Kinabalu fetch the overall diagnosis and decide who the DPI should be assigned to. More on this will be covered in Part III.

Here’s a simplified example of a contract for a data-lake table:

{
  "specification_version": 1,
  "asset_urn": "urn:li:dataset:(urn:li:dataPlatform:hive,genchi.validation_jobs,PROD)",
  "entity_type": "datalake_table",
  "health_url": "https://example-hugo.grab.com/assets/genchi.validation_jobs/health",
  "contract_details": {
    "contact": {
      "oncall_group": "oncall-genchi",
      "slack_channel": "ask-genchi"
    },
    "terms": {
      "usage": "Source of truth for all genchi validation jobs.",
      "limitations": "Not suitable for real-time use cases.",
      "notice_period_in_days": 14
    },
    "schema": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_schema_test/health",
        "uid": "fundamental_schema_test",
        "version": 1
      }

    ],
    "sla": {
      "freshness": [
        {
          "type": "genchi",
          "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_freshness_test/health",
          "uid": "fundamental_freshness_test",
          "version": 1
        }
      ],
      "lifecycle": null
    },
    "data_quality": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_completeness_test/health",
        "uid": "fundamental_completeness_test",
        "version": 1
      }
    ]
  }
}

The contract in the registry only stores references to enforceable rules, which are an identifier and version, like the example above, rather than the full configuration body. This keeps contracts lightweight and tool-agnostic, while giving rule-enforcement tools (Genchi for data-quality tests, Ouroboros for table lifecycle) and Kinabalu a stable handle to resolve the actual rule definition in their own systems, without duplicating configuration or letting it drift across platforms.

Conclusion

By bringing Hubble, Genchi, and the Data Contract Registry together, we provide the foundational tools to build trust in certified data assets. Hubble enables discovery and establishes domains and ownership; the Data Contract Registry captures explicit expectations between producers and consumers; and Genchi continuously validates those promises with tests on freshness, volume, schema, and business rules. Hubble’s certification engine then evaluates these ownership, contract, and quality signals to decide whether an asset meets Grab’s standards and surfaces that as a visible certification state. As a result, consumers can confidently default to certified assets, usage converges on a smaller, better-governed pool of datasets, and certification becomes a mechanism that changes producer behavior and guides consumer choice. We saw this convergence in practice. In just one year since the Signals Marketplace campaign began in 2024, the number of P80 datasets (the most used tables that account for 80% of all queries) has dropped by over 58%.

This data foundation is especially important in an AI-first future for Grab. Certified streams, tables, metrics, and attributes give AI agents and automated analytics a default substrate they can rely on. With Hubble and Genchi, data producers have clear ownership, contracts, and observability. Data consumers can discover and trust certified assets without guesswork, and platform teams can measure and improve Signals Marketplace health over time (for example, queries on certified assets, lineage depth, and cost). Together, these capabilities turn “data mesh” from a slogan into an operational, AI-ready marketplace of reliable, reusable signals that power decisions across Grab.

Figure 7. Building trust in certified data assets through discovery, contracts, and continuous validation.

What’s next

In the next blog, we’ll zoom into the DPI process itself with Kinabalu as the incident lifecycle orchestrator:

  • How Genchi test failures and data contract breaches turn into DPIs.
  • How DPI is assigned based on root causes and what sets the priority level.
  • The patterns we’ve seen in “noisy” vs actionable DPIs, and what we’ve changed in our platforms.
  • How we’re using automation and agents to reduce DPI toil and close the loop back into certification.

We’ll walk through concrete case studies showing how a single broken table moves from first failure, to diagnosis and fix, to updated contracts and a more resilient certified data asset.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
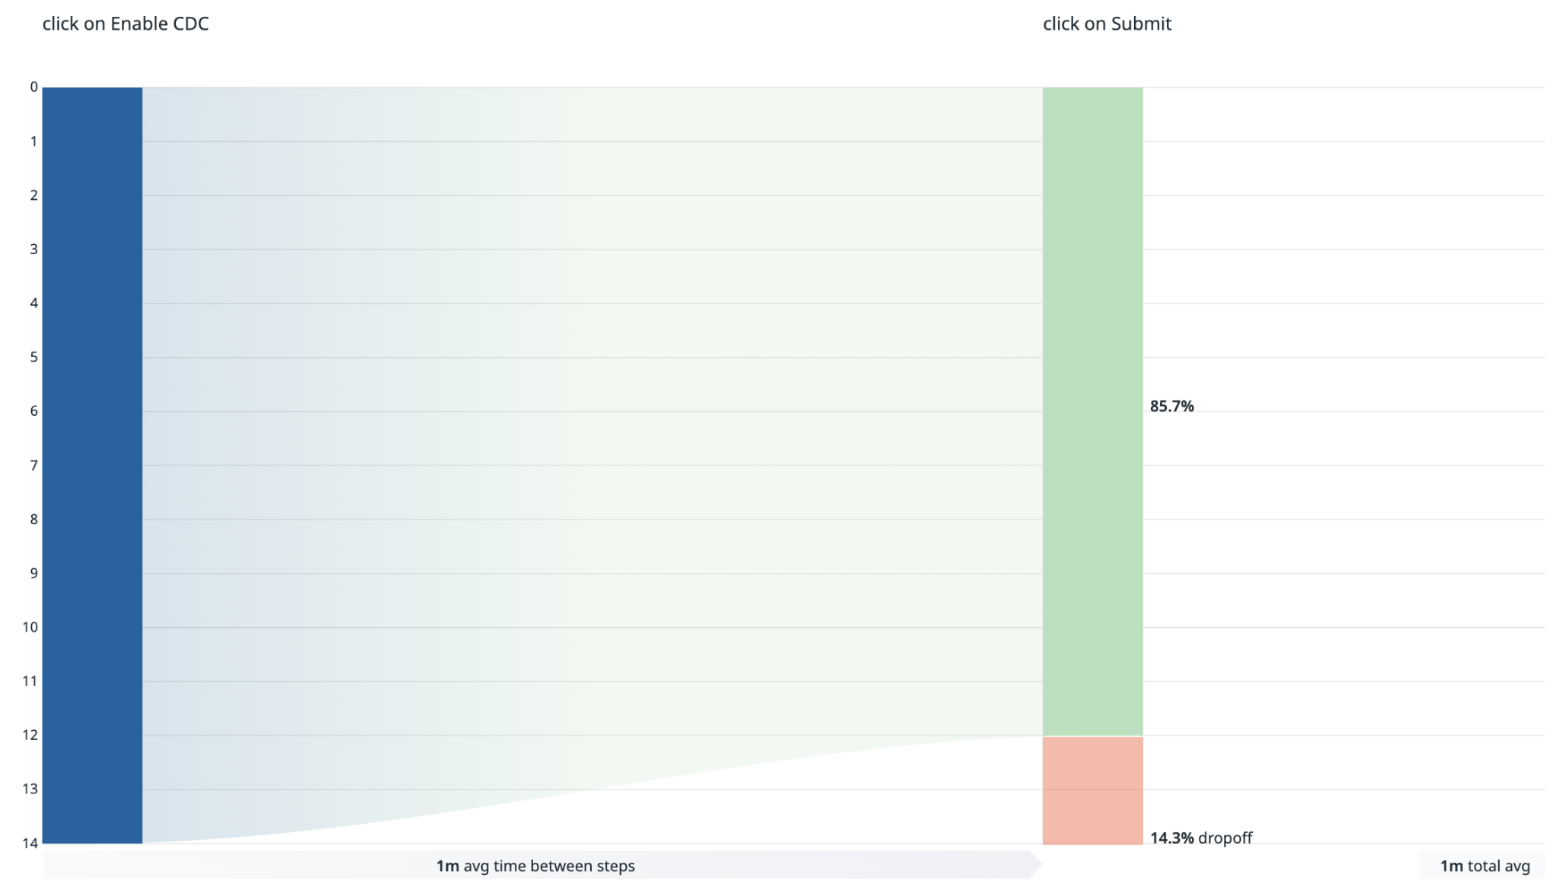
Scaling Global Storytelling: Modernizing Localization Analytics at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/scaling-global-storytelling-modernizing-localization-analytics-at-netflix-816f47290641

Valentin Geffrier, Tanguy Cornuau

Each year, we bring the Analytics Engineering community together for an Analytics Summit — a multi-day internal conference to share analytical deliverables across Netflix, discuss analytic practice, and build relationships within the community. This post is one of several topics presented at the Summit highlighting the breadth and impact of Analytics work across different areas of the business.

At Netflix, our goal is to entertain the world, which means we must speak the world’s languages. Given the company’s growth to serving 300 million+ members in more than 190+ countries and 50+ languages, the Localization team has had to scale rapidly in creating more dubs and subtitle assets than ever before. However, this growth created technical debt within our systems: a fragmented landscape of analytics workflows, duplicated pipelines, and siloed dashboards that we are now actively modernizing.

The Challenge: “Who Made This Dub?”

Historically, business logic for localization metrics was replicated across isolated domains. A question as simple as “Who made this dub/subtitle?” is actually complex — it requires mapping multiple data sources through intricate and constantly changing logic, which varies depending on the specific language asset type and creation workflow.

When this logic is copied into isolated pipelines for different use cases it creates two major risks: inconsistency in reporting and a massive maintenance burden whenever upstream logic changes. We realized we needed to move away from these vertical silos.

Our Modernization Strategy

To address this, we defined a vision centered on consolidation, standardization, and trust, executed through three strategic pillars:

1. The Audit and Consolidation Playbook

We initiated a comprehensive audit of over 40 dashboards and tools to assess usage and code quality. Our focus has shifted from patching frontend visualizations to consolidating backend pipelines. For example, we are currently merging three legacy dashboards related to dubbing partner KPIs (around operational performance, capacity, and finances), focusing first on a unified data and backend layer that can support a variety of future frontend iterations.

2. Reducing “Not-So-Tech” Debt

Technical debt isn’t just about code; it is also about the user experience. We define “Not-So-Tech Debt” as the friction stakeholders feel when tools are hard to interpret or can benefit from better storytelling. To fix this, we revamped our Language Asset Consumption tool — instead of reporting dub and subtitle metrics independently, we combine audio and text languages into one consumption language that helps differentiate Original Language versus Localized Consumption and measure member preferences between subtitles, dubs, or a combination of both for a given language. This unlocks more intuitive insights based on actual recurring stakeholder use cases.

3. Investing in Core Building Blocks

We are shifting to a write once, read many architecture. By centralizing business logic into unified tables — such as a “Language Asset Producer” table — we solve the “Who made this dub?” problem once. This centralized source now feeds into multiple downstream domains, including our Dub Quality and Translation Quality metrics, ensuring that any logic update propagates instantly across the ecosystem.

The Future: Event-Level Analytics

Looking ahead, we are moving beyond asset-level metrics to event-level analytics. We are building a generic data model to capture granular timed-text events, such as individual subtitle lines. This data helps us understand how subtitle characteristics (e.g. reading speed) affect member engagement and, in turn, refine the style guidelines we provide to our subtitle linguists to improve the member experience with localized content.

Ultimately, this modernization effort is about scaling our ability to measure and enhance the joy and entertainment we deliver to our diverse global audience, ensuring that every member, regardless of their language, has the best possible Netflix experience.


Scaling Global Storytelling: Modernizing Localization Analytics at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Human Native is joining Cloudflare

Post Syndicated from Will Allen original https://blog.cloudflare.com/human-native-joins-cloudflare/

Today, we’re excited to share that Cloudflare has acquired Human Native, a UK-based AI data marketplace specializing in transforming multimedia content into searchable and useful data.

Human Native x Cloudflare

The Human Native team has spent the past few years focused on helping AI developers create better AI through licensed data. Their technology helps publishers and developers turn messy, unstructured content into something that can be understood, licensed and ultimately valued. They have approached data not as something to be scraped, but as an asset class that deserves structure, transparency and respect.

Access to high-quality data can lead to better technical performance. One of Human Native’s customers, a prominent UK video AI company, threw away their existing training data after achieving superior results with data sourced through Human Native. Going forward they are only training on fully licensed, reputably sourced, high-quality content.

This gives a preview of what the economic model of the Internet can be in the age of generative AI: better AI built on better data, with fair control, compensation and credit for creators.

The Internet needs new economic models

For the last 30 years, the open Internet has been based on a fundamental value exchange: creators create content, aggregators (such as search engines or social media) send traffic. Creators can monetize that traffic through advertisements, subscriptions or direct support. This is the economic loop that has powered the explosive growth of the Internet.

But it’s under real strain.

Crawl-to-referral ratios are skyrocketing, with 10s of thousands of AI and bot crawls per real human visitor, and it’s unclear how multipurpose crawlers are using the content they access.

The community of creators who publish on the Internet is a diverse group: news publishers, content creators, financial professionals, technology companies, aggregators and more. But they have one thing in common: They want to decide how their content is used by AI systems.

Cloudflare’s work in building AI Crawl Control and Pay Per Crawl is predicated on a simple philosophy: Content owners should get to decide how and when their content is accessed by others. Many of our customers want to optimize their brand and content to make sure it is in every training data set and shows up in every new search; others want to have more control and only allow access if there is direct compensation.

Our tools like AI Search, AI Crawl Control and Pay Per Crawl can help, wherever you land in that equation. The important thing is that the content owner gets to decide.

New tools for AI developers

With the Human Native team joining Cloudflare, we are accelerating our work in helping customers transform their content to be easily accessed and understood by AI bots and agents in addition to their traditional human audiences.

Crawling is complex, expensive in terms of engineering and compute to process the content, and has no guarantees of quality control. A crawled index can contain duplicates, spam, illegal material and many more headaches. Developers are left with messy, unstructured data.

We recently announced our work in building the AI Index, a powerful new way for both foundation model companies and agents to access content at scale.

Instead of sending crawlers blindly and repeatedly across the open Internet, AI developers will be able to connect via a pub/sub model: participating websites will expose structured updates whenever their content changes, and developers will be able to subscribe to receive those updates in real time. 

This opens up new avenues for content creators to experiment with new business models. 

Building the foundation for these new business models

Cloudflare is investing heavily in creating the foundations for these new business models, starting with x402.

We recently announced that we are creating the x402 Foundation, in partnership with Coinbase, to enable machine-to-machine transactions for digital resources.

Payments on the web have historically been designed for humans. We browse a merchant’s website, show intent by adding items to a cart, and confirm our intent to purchase by putting in our credit card information and clicking “Pay.” But what if you want to enable direct transactions between automated systems? We need protocols to allow machine-to-machine transactions. 

Together, Human Native and Cloudflare will accelerate our work in building the basis of these new economic models for the Internet. 

What’s next

The Internet works best when it is open, fair, and independently sustainable. We’re excited to welcome the Human Native team to Cloudflare, and even more excited about what we will build together to improve the foundations of the Internet in the age of AI.

Onwards.

Announcing support for GROUP BY, SUM, and other aggregation queries in R2 SQL

Post Syndicated from Jérôme Schneider original https://blog.cloudflare.com/r2-sql-aggregations/

When you’re dealing with large amounts of data, it’s helpful to get a quick overview — which is exactly what aggregations provide in SQL. Aggregations, known as “GROUP BY queries”, provide a bird’s eye view, so you can quickly gain insights from vast volumes of data.

That’s why we are excited to announce support for aggregations in R2 SQL, Cloudflare’s serverless, distributed, analytics query engine, which is capable of running SQL queries over data stored in R2 Data Catalog. Aggregations will allow users of R2 SQL to spot important trends and changes in the data, generate reports and find anomalies in logs.

This release builds on the already supported filter queries, which are foundational for analytical workloads, and allow users to find needles in haystacks of Apache Parquet files.

In this post, we’ll unpack the utility and quirks of aggregations, and then dive into how we extended R2 SQL to support running such queries over vast amounts of data stored in R2 Data Catalog.

The importance of aggregations in analytics

Aggregations, or “GROUP BY queries”, generate a short summary of the underlying data.

A common use case for aggregations is generating reports. Consider a table called “sales”, which contains historical data of all sales across various countries and departments of some organisation. One could easily generate a report on the volume of sales by department using this aggregation query:

SELECT department, sum(value)
FROM sales
GROUP BY department

The “GROUP BY” statement allows us to split table rows into buckets. Each bucket has a label corresponding to a particular department. Once the buckets are full, we can then calculate “sum(value)” for all rows in each bucket, giving us the total volume of sales performed by the corresponding department.

For some reports, we might only be interested in departments that had the largest volume. That’s where an “ORDER BY” statement comes in handy:

SELECT department, sum(value)
FROM sales
GROUP BY department
ORDER BY sum(value) DESC
LIMIT 10

Here we instruct the query engine to sort all department buckets by their total sales volume in the descending order and only return the top 10 largest.

Finally, we might be interested in filtering out anomalies. For example, we might want to only include departments that had more than five sales total in our report. We can easily do that with a “HAVING” statement:

SELECT department, sum(value), count(*)
FROM sales
GROUP BY department
HAVING count(*) > 5
ORDER BY sum(value) DESC
LIMIT 10

Here we added a new aggregate function to our query — “count(*)” — which calculates how many rows ended up in each bucket. This directly corresponds to the number of sales in each department, so we have also added a predicate in the “HAVING” statement to make sure that we only leave buckets with more than five rows in them.

Two approaches to aggregation: compute sooner or later

Aggregation queries have a curious property: they can reference columns that are not stored anywhere. Consider “sum(value)”: this column is computed by the query engine on the fly, unlike the “department” column, which is fetched from Parquet files stored on R2. This subtle difference means that any query that references aggregates like “sum”, “count” and others needs to be split into two phases.

The first phase is computing new columns. If we are to sort the data by “count(*)” column using “ORDER BY” statement or filter rows based on it using “HAVING” statement, we need to know the values of this column. Once the values of columns like “count(*)” are known, we can proceed with the rest of the query execution.

Note that if the query does not reference aggregate functions in “HAVING” or “ORDER BY”, but still uses them in “SELECT”, we can make use of a trick. Since we do not need the values of aggregate functions until the very end, we can compute them partially and merge results just before we are about to return them to the user.

The key difference between the two approaches is when we compute aggregate functions: in advance, to perform some additional computations on them later; or on the fly, to iteratively build results the user needs.

First, we will dive into building results on the fly — a technique we call “scatter-gather aggregations.” We will then build on top of that to introduce “shuffling aggregations” capable of running extra computations like “HAVING” and “ORDER BY” on top of aggregate functions.

Scatter-gather aggregations

Aggregate queries without “HAVING” and “ORDER BY” can be executed in a fashion similar to filter queries. For filter queries, R2 SQL picks one node to be the coordinator in query execution. This node analyzes the query and consults R2 Data Catalog to figure out which Parquet row groups may contain data relevant to the query. Each Parquet row group represents a relatively small piece of work that a single compute node can handle. Coordinator node distributes the work across many worker nodes and collects results to return them to the user.

In order to execute aggregate queries, we follow all the same steps and distribute small pieces of work between worker nodes. However, this time instead of just filtering rows based on the predicate in the “WHERE” statement, worker nodes also compute pre-aggregates.

Pre-aggregates represent an intermediary state of an aggregation. This is an incomplete piece of data representing a partially computed aggregate function on a subset of data. Multiple pre-aggregates can be merged together to compute the final value of an aggregate function. Splitting aggregate functions into pre-aggregates allows us to horizontally scale computation of aggregation, making use of vast compute resources available in Cloudflare’s network.


For example, pre-aggregate for “count(*)” is simply a number representing the count of rows in a subset of data. Computing the final “count(*)” is as easy as adding these numbers together. Pre-aggregate for “avg(value)” consists of two numbers: “sum(value)” and “count(*)”. The value of “avg(value)” can then be computed by adding together all “sum(value)” values, adding together all “count(*)” values and finally dividing one number by the other.

Once worker nodes have finished computing the pre-aggregates, they stream results to the coordinator node. The coordinator node collects all results, computes final values of aggregate functions from pre-aggregates, and returns the result to the user.

Shuffling, beyond the limits of scatter-gather

Scatter-gather is highly efficient when the coordinator can compute the final result by merging small, partial states from workers. If you run a query like SELECT sum(sales) FROM orders, the coordinator receives a single number from each worker and adds them up. The memory footprint on the coordinator is negligible regardless of how much data resides in R2.

However, this approach becomes inefficient when the query requires sorting or filtering based on the result of an aggregation. Consider this query, which finds the top two departments by sales volume:

SELECT department, sum(sales)
FROM sales
GROUP BY department
ORDER BY sum(sales) DESC
LIMIT 2

Correctly determining the global Top 2 requires knowing the total sales for every department across the entire dataset. Because the data is spread effectively at random across the underlying Parquet files, sales for a specific department are likely split across many different workers. A department might have low sales on every individual worker, excluding it from any local Top 2 list, yet have the highest sales volume globally when summed together.

The diagram below illustrates how a scatter-gather approach would not work for this query. “Dept A” is the global sales leader, but because its sales are evenly spread across workers, it doesn’t make to some local Top 2 lists, and ends up being discarded by the coordinator.


Consequently, when the query orders results by their global aggregation, the coordinator cannot rely on pre-filtered results from workers. It must request the total count for every department from every worker to calculate the global totals before it can sort them. If you are grouping by a high-cardinality column like IP addresses or User IDs, this forces the coordinator to ingest and merge millions of rows, creating a resource bottleneck on a single node.

To solve this, we need shuffling, a way to colocate data for specific groups before the final aggregation occurs.

Shuffling of aggregation data

To address the challenges of random data distribution, we introduce a shuffling stage. Instead of sending results to the coordinator, workers exchange data directly with each other to colocate rows based on their grouping key.

This routing relies on deterministic hash partitioning. When a worker processes a row, it hashes the GROUP BY column to identify the destination worker. Because this hash is deterministic, every worker in the cluster independently agrees on where to send specific data. If “Engineering” hashes to Worker 5, every worker knows to route “Engineering” rows to Worker 5. No central registry is required.

The diagram below illustrates this flow. Notice how “Dept A” starts on Workers 1, 2 and 3. Because the hash function maps “Dept A” to Worker 1, all workers route those rows to that same destination.


Shuffling aggregates produces the correct results. However, this all-to-all exchange creates a timing dependency. If Worker 1 begins calculating the final total for “Dept A” before Worker 3 has finished sending its share of the data, the result will be incomplete.

To address this, we enforce a strict synchronization barrier. The coordinator tracks the progress of the entire cluster while workers buffer their outgoing data and flush it via gRPC streams to their peers. Only when every worker confirms that it has finished processing its input files and flushing its shuffle buffers does the coordinator issue the command to proceed. This barrier guarantees that when the next stage begins, the dataset on each worker is complete and accurate.

Local finalization

Once the synchronization barrier is lifted, every worker holds the complete dataset for its assigned groups. Worker 1 now has 100% of the sales records for “Dept A” and can calculate the final total with certainty.

This allows us to push computational logic like filtering and sorting down to the worker rather than burdening the coordinator. For example, if the query includes HAVING count(*) > 5, the worker can filter out groups that do not meet this criteria immediately after aggregation.

At the end of this stage, each worker produces a sorted, finalized stream of results for the groups it owns.

The streaming merge

The final piece of the puzzle is the coordinator. In the scatter-gather model, the coordinator was responsible for the expensive task of aggregating and sorting the entire dataset. In the shuffling model, its role changes.

Because the workers have already computed the final aggregates and sorted them locally, the coordinator only needs to perform a k-way merge. It opens a stream to every worker and reads the results row by row. It compares the current row from each worker, picks the “winner” based on the sort order, and adds it to the query results that will be sent to the user.

This approach is particularly powerful for LIMIT queries. If a user asks for the top 10 departments, the coordinator merges the streams until it has found the top 10 items and then immediately stops processing. It does not need to load or merge the millions of remaining rows, allowing for greater scale of operation without over-consumption of compute resources.

A powerful engine for processing massive datasets

With the addition of aggregations, R2 SQL transforms from a tool great for filtering data into a powerful engine capable of data processing on massive datasets. This is made possible by implementing distributed execution strategies like scatter-gather and shuffling, where we are able to push the compute to where the data lives, using the scale of Cloudflare’s global compute and network. 

Whether you are generating reports, monitoring high-volume logs for anomalies, or simply trying to spot trends in your data, you can now easily do it all within Cloudflare’s Developer Platform without the overhead of managing complex OLAP infrastructure or moving data out of R2.

Try it now

Support for aggregations in R2 SQL is available today. We are excited to see how you use these new functions with data in R2 Data Catalog.

  • Get Started: Check out our documentation for examples and syntax guides on running aggregation queries.

  • Join the Conversation: If you have questions, feedback, or want to share what you’re building, join us in the Cloudflare Developer Discord.

A Decade of Defense: Celebrating Grab’s 10th Year Bug Bounty Program

Post Syndicated from Grab Tech original https://engineering.grab.com/a-decade-of-defense

Introduction

Ten years ago, we launched our bug bounty program in partnership with HackerOne. Beyond a security initiative, it represented an open invitation to collaborative development.
As pioneers in Southeast Asia, we began the program with 23 initial researchers, and it has since evolved into a global community of security researchers.

The strategic structure and scope of our Bug Bounty Program, combined with our continuous innovation and experimentation, have successfully captured the attention of the global security research community. Over the past decade, we have partnered with more than 850 active security researchers from HackerOne’s community of over 2 million cybersecurity professionals worldwide. These dedicated researchers work alongside us across borders and time zones, forming a collaborative defense network that helps protect over 187 million users throughout Southeast Asia. Their ongoing participation demonstrates both the maturity of our program and the trust we’ve built within the security research community.

This milestone reflects the strength of shared purpose and our sustained partnership with the HackerOne platform. It demonstrates the value of human connection and the collective understanding that security is stronger through collaboration. Here’s to a decade of partnership and to many more years of building a safer future, one collaboration at a time!

Figure 1. Ten years of achievements with our HackerOne partnership.

Evolution and growth: Adapting to a dynamic threat landscape

Over the past ten years, our program has consistently adapted to the dynamic threat landscape and integrated invaluable feedback from our research community. We have grown from a private initiative to a program that consistently ranks among the top 20 worldwide and among the top 3 in Asia on HackerOne. Key milestones from our journey include:

  • Expanding our horizons: Our scope significantly broadened in 2023-2024, continuously adding new assets and prominently including financial services in Indonesia and AI systems. This expansion provides researchers with more avenues to contribute to Grab’s security.
  • Focused mobile security: We introduced a dedicated bounty table for mobile-specific issues, recognizing the unique challenges of mobile security.
  • Incentivizing excellence: We regularly experiment with campaigns of various types and targets, diversifying our reward methods to include both financial rewards and recognition.
  • Evolving vulnerability focus: We’ve observed a significant shift in the types of vulnerabilities reported over the decade, moving from foundational issues in early years to more sophisticated and emerging categories recently.
Figure 2. The journey of our bug bounty program.

The global stage: Connecting with the best

Our program’s success is deeply rooted in its vibrant global community, which we actively foster through continuous engagement. Our strategy extends beyond the platform to major live hacking events, including the ThreatCon Live Hacking Event 2023 in Nepal and DEFCON 32’s Live Recon Village 2024 in Las Vegas. These initiatives have been instrumental in connecting us with a diverse pool of new talent and strengthening relationships with researchers across different continents. By meeting hackers where they are, we’ve not only brought new expertise into our ecosystem but also demonstrated our commitment to being an accessible and collaborative partner on a global scale.

The high participation and quality submissions from these events demonstrate the effectiveness of this approach. They’ve expanded our global security testing coverage and strengthened our standing within the worldwide cybersecurity community. Through ongoing interactions and submitted reports, we continue to see that security is a collaborative effort with no borders.

Exclusive anniversary celebrations: Global club campaigns

To commemorate our 10th anniversary, we launched three exclusive, invite-only campaigns with HackerOne’s regional clubs in Germany, Morocco, and India. These campaigns served as cultural exchanges, bringing fresh perspectives from outside our core Southeast Asian consumer markets. By engaging with these clubs, we expanded our researcher community and connected with security experts who understand different threat landscapes and methodologies, bringing outside perspectives to our systems.

In August, we also ran a broader anniversary campaign that drew significant participation from the researcher community, resulting in 461 submissions. xchopath was awarded the Best Hacker Bonus for their contributions during this campaign.

These campaigns expanded our global security testing coverage and strengthened relationships with international researcher communities. Beyond vulnerability reports, they functioned as knowledge-sharing initiatives. We connected directly with researchers to learn from their experience and feedback, creating a continuous loop of improvement. This international collaboration also informed our global expansion security strategy by providing insights into how different regions approach digital payments and authentication.

The anniversary campaigns allowed us to validate our security frameworks against diverse regulatory environments and advanced testing methodologies from established security markets, reinforcing our commitment to maintaining robust security standards.

Voices from our community

Behind every vulnerability report is a researcher who chose to help make Grab safer. Their perspectives reveal the human side of our security evolution. These individuals are not just cybersecurity experts; they are partners in our mission to protect millions of users and ensure a safe digital environment. Here are a few testimonies from participants in our past campaigns:

  • “The triage was very fast despite the time difference, which I really appreciated. The triaging experience was better than other programs. The huge scope and business portal with different user roles made it especially interesting to explore.” – ArtSec [H1 Germany club campaign participant]

  • “I liked that different countries have different features—this gives me more attack surface to explore. Response time was great, triage was very fast, and I appreciated Grab’s effort in providing fast responses. The scope was huge with a lot of wildcards for reconnaissance.” – Sicksec [H1 Morocco club campaign participant]

  • “More than 20 bugs were reported, and was particularly happy that bounties were being paid upon triage. The Germany team spent a lot of time on the educational part, especially for newcomers. Communication overall was very good, and the immediate response even outside working hours was really cool. SSO and authentication is my expertise and I liked that aspect of exploring the platform.” – Lauritz [H1 Germany club campaign participant]

The road ahead: Our commitment to a secure future

With a strong community of security researchers across countries and a decade of collaboration, we’ve built meaningful partnerships. Every vulnerability report represents trust, and every discovery reflects dedication to our shared mission. The program demonstrates our choice to build together rather than work in isolation, to protect rather than exploit, and to collaborate rather than compete.

While we celebrate our external community, the success of our program relies equally on our dedicated internal teams. Our cybersecurity teams form the operational foundation of this initiative. Their consistent responsiveness and researcher-focused approach have enabled vulnerability reporting to evolve into a genuine partnership, maintaining researcher trust and keeping Grab secure.

The next ten years will bring challenges we can’t yet imagine, from emerging threats in artificial intelligence to novel cryptographic approaches in a quantum-powered world. We will face them together as a community that spans cultures, time zones, and expertise.

Together, we’ll continue securing Southeast Asia’s digital future, one partnership, one discovery, one shared achievement at a time.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
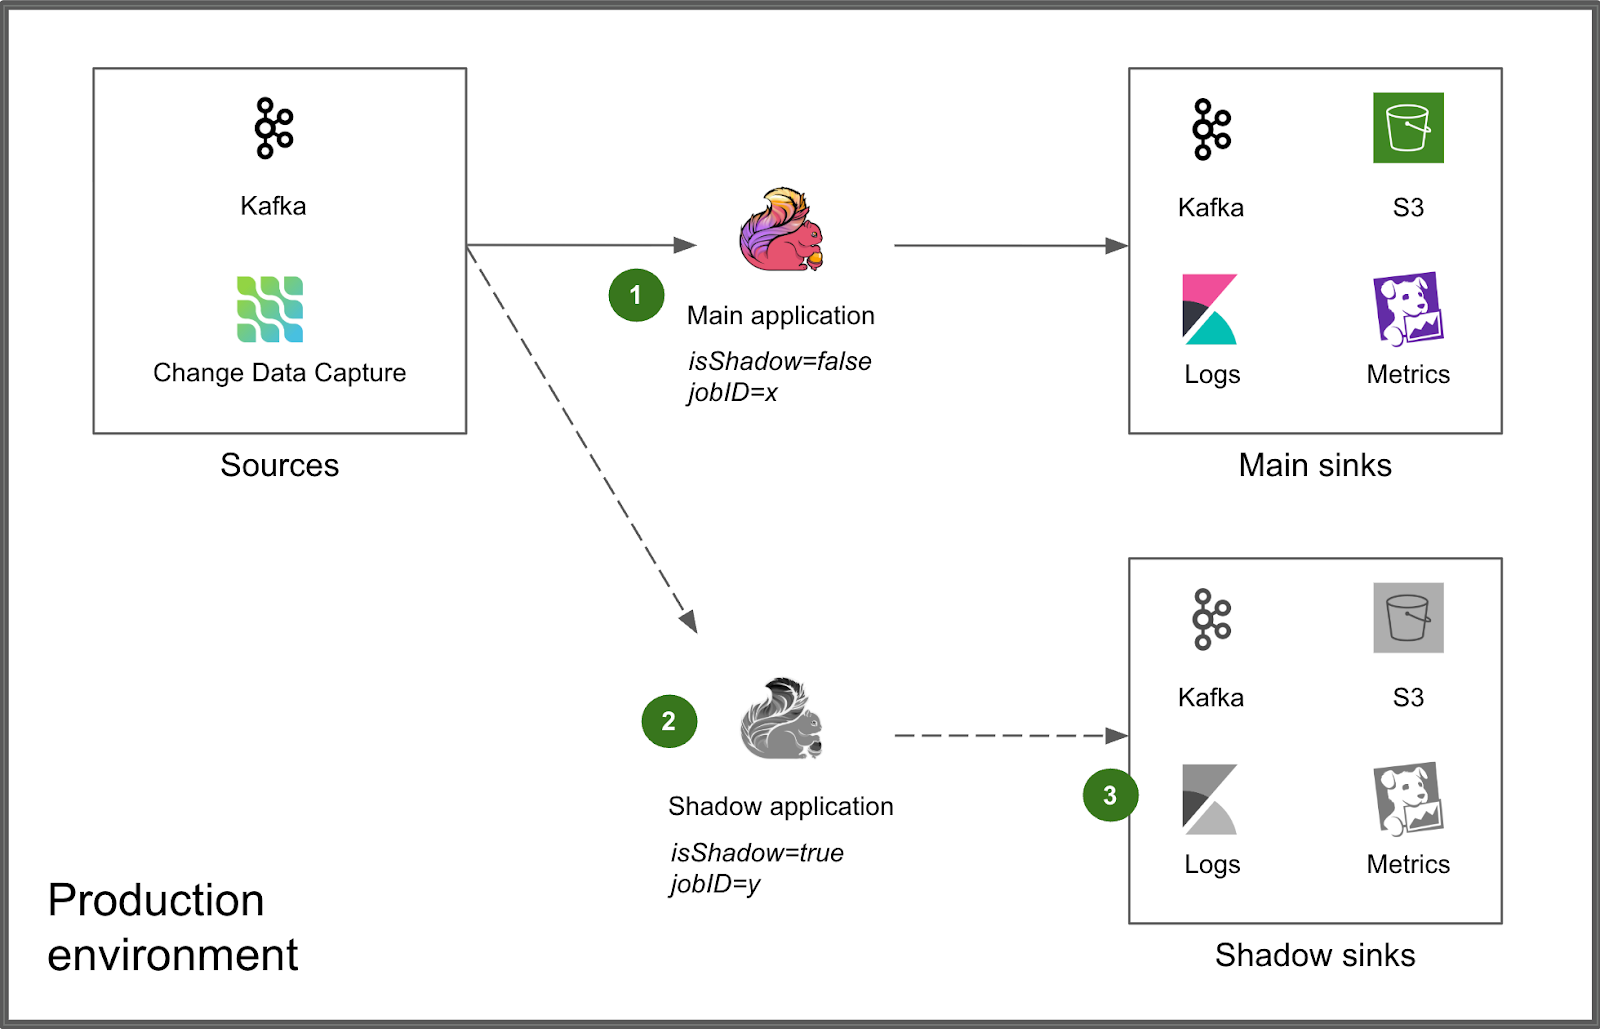
Real-time data quality monitoring: Kafka stream contracts with syntactic and semantic test

Post Syndicated from Grab Tech original https://engineering.grab.com/real-time-data-quality-monitoring

Introduction

In today’s data-driven landscape, monitoring data quality has become a critical need for ensuring reliable and efficient data usage across domains. High-quality data is the backbone of AI innovation, driving efficiency and unlocking new opportunities. As decentralized data ownership grows, the ability to effectively monitor data quality is essential for maintaining reliability in data systems.

Kafka streams, as a vital component of real-time data processing, play a significant role in this ecosystem. However, unreliable data within Kafka streams can lead to errors and inefficiencies for downstream users, and monitoring the quality of data within these streams has always been a challenge. This blog introduces a solution that empowers stream users to define a data contract, specifying the rules that Kafka stream data must adhere to. By leveraging this user-defined data contract, the solution performs automated real-time data quality checks, identifies problematic data as it occurs, and promptly notifies stream owners. This ensures timely action, enabling effective monitoring and management of Kafka stream data quality while supporting the broader goals of data mesh and AI-driven innovation.

Problem statement

In the past, monitoring Kafka stream data processing lacked an effective solution for data quality validation. This limitation made it challenging to identify bad data, notify users in a timely manner, and prevent the cascading impact on downstream users from further escalating.

Challenges in syntactic and semantic issue identification:

  • Syntactic issues: Refers to schema mismatches between producers and consumers, which can lead to deserialization errors. While schema backward compatibility can be validated upon schema evolution, there are scenarios where the actual data in the Kafka topic does not align with the defined schema. For example, this can occur when a rogue Kafka producer is not using the expected schema for a given Kafka topic. Identifying the specific fields causing these syntactic issues is a typical challenge.
  • Semantic issues: Refers to inconsistencies or misalignments between producers and consumers about the expected pattern or significance of each field. Unlike Kafka stream schemas, which act as a data structure contract between producers and consumers, there is no existing framework for stakeholders to define and enforce field-level semantic rules, for example, the expected length or pattern of an identifier.

Timeliness challenge in data quality monitoring: There is no real-time mechanism to automatically validate data against predefined rules, timely identify quality issues, and promptly alert stream stakeholders. Without real-time stream validation, data quality issues can sometimes persist for periods of time, impacting various online and offline downstream systems before being discovered.

Observability challenge for troubleshooting bad data: Even when problematic data is identified, stream users face difficulties in pinpointing the exact “poison data” and understanding which fields are incompatible with the schema or violate semantic rules. This lack of visibility complicates Root Cause Analysis and resolution efforts.

Solution

Our Coban platform offers a standardized data quality test and observability solution at the platform level, consisting of the following components:

  • Data Contract Definition: Enables Kafka stream stakeholders to define contracts that include schema agreements, semantic rules that Kafka topic data must comply with, and Kafka stream ownership details for alerting and notifications.
  • Automated Test Execution: Provides a long running Test Runner to automatically execute real-time tests based on the defined contract.
  • Real-time Data Quality Issue Identification: Detects data issues at both syntactic and semantic levels in real-time.
  • Alerts and Result Observability: Alerts users, simplifying observation of data quality issues via the platform.

Architecture details

The solution includes three components: Data Contract Definition, Test Execution & Data Quality Issue Identification, and Result Observability as shown in the architecture diagram in figure 1. All mentions of “Flow” from here onwards refer to the corresponding processes illustrated in figure 1.

Figure 1. Real-time Kafka Stream Data Quality Monitoring Architecture diagram.

Data Contract Definition

The Coban Platform streamlines the process of defining Kafka stream data contracts, serving as a formal agreement among Kafka stream stakeholders. This includes the following components:

  • Kafka Stream Schema: Represents the schema used by the Kafka topic under test and helps the Test Runner to validate schema compatibility across data streams (Flow 1.1).
  • Kafka Stream Configuration: Encompasses essential configurations such as the endpoint and topic name, which the platform automatically populates (Flow 1.2).
  • Observability Metadata: Provides contact information for notifying Kafka stream stakeholders about data quality issues and includes alert configurations for monitoring (Flow 1.3).
  • Kafka Stream Semantic Test Rules: Empowers users to define intuitive semantic test rules at the field level. These rules include checks for string patterns, number ranges, constant values, etc. (Flow 1.5).
  • LLM-Based Semantic Test Rules Recommendation: Defining dozens if not hundreds of field-specific test rules can overwhelm users. To simplify this process, the Coban Platform uses LLM-based recommendations to predict semantic test rules using provided Kafka stream schemas and anonymized sample data (Flow 1.4). This feature helps users set up semantic rules efficiently, as demonstrated in the sample UI in figure 2.
Figure 2. Sample UI showcasing LLM-based Kafka stream schema field-level semantic test rules. Note that the data shown is entirely fictional.

Data Contract Transformation

Once defined, the Coban Platform’s transformation engine converts the data contract into configurations that the Test Runner can interpret (Flow 2.1). This transformation process includes:

  • Kafka Stream Schema: Translates the schema defined in the data contract into a schema reference that the Test Runner can parse.
  • Kafka Stream Configuration: Sets up the Kafka stream as a source for the Test Runner.
  • Observability metadata: Sets contact information as configurations of the Test Runner.
  • Kafka Stream Semantic Test Rules: Transforms human-readable semantic test rules into an inverse SQL query to capture the data that violates the defined rules.
Figure 3. Illustration of semantic test rules being converted from human-readable formats into inverse SQL queries.

Test Execution & Data Quality Issue Identification

Once the Test Configuration Transformation Engine generates the Test Runner configuration (Flow 2.1), the platform automatically deploys the Test Runner.

Test Runner

The Test Runner utilises FlinkSQL as the compute engine to execute the tests. FlinkSQL was selected for its flexibility in defining test rules as straightforward SQL statements, enabling our platform to efficiently convert data contracts into enforceable rules.

Test Execution Workflow And Problematic Data Identification

FlinkSQL consumes data from the Kafka topic under test (Flow 2.2) using its own consumer group, ensuring it doesn’t impact other consumers. It runs the inverse SQL query (Flow 2.3) to identify any data that violates the semantic rules or that is syntactically incorrect in the first place. Test Runner captures such data, packages it into a data quality issue event enriched with a test summary, the total count of bad records, and sample bad data, and publishes it to a dedicated Kafka topic (Flow 3.2). Additionally, the platform sinks all such data quality events to an AWS S3 bucket (Flow 3.1) to enable deeper observability and analysis.

Result Observability

Grab’s in-house data quality observability platform, Genchi, consumes problematic data captured by the Test Runner (Flow 3.3).

Alerting

Genchi sends Slack notifications (Flow 3.5) to stream owners specified in the data contract observability metadata. These notifications include detailed information about stream issues, such as links to sample data in Coban UI, observed windows, counts of bad records, and other relevant details.

Figure 4. Sample Slack notifications

Observability

Users can access the Coban UI (Flow 3.4), displaying Kafka stream test rules and sample bad records, highlighting fields and values that violate rules.

Figure 5. In this Sample Test Result, the highlighted fields indicate violations of the semantic test rules.

Impact

Since its deployment earlier this year, the solution has enabled Kafka stream users to define contracts with syntactic and semantic rules, automate test execution, and alert users when problematic data is detected, prompting timely action. It has been actively monitoring data quality across 100+ critical Kafka topics. The solution offers the capability to immediately identify and halt the propagation of invalid data across multiple streams.

Conclusion

We implemented and rolled out a solution to assist Grab engineers in effectively monitoring data quality in their Kafka streams. This solution empowers them to establish syntactic and semantic tests for their data. Our platform’s automatic testing feature enables real-time tracking of data quality, with instant alerts for any discrepancies. Additionally, we provide detailed visibility into test results, facilitating the easy identification of specific data fields that violate the rules. This accelerates the process of diagnosing and resolving issues, allowing users to swiftly address production data challenges.

What’s next

While our current solution emphasizes monitoring the quality of Kafka streaming data, further exploration will focus on tracing producers to pinpoint the origin of problematic data, as well as enabling more advanced semantic tests such as cross-field validations. Additionally, we aim to expand monitoring capabilities to cover broader aspects like data completeness and freshness, and integrate with Gable AI to detect Data Transfer Object (DTO) changes and semantic regressions in Go producers upon committing code to the Git repository. These enhancements will pave the way for a more robust, multidimensional data quality testing solution across a wider range.

References

Driving Data Quality with Data Contracts: A Comprehensive Guide to Building Reliable, Trusted, and Effective Data Platforms by Andrew Jones

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
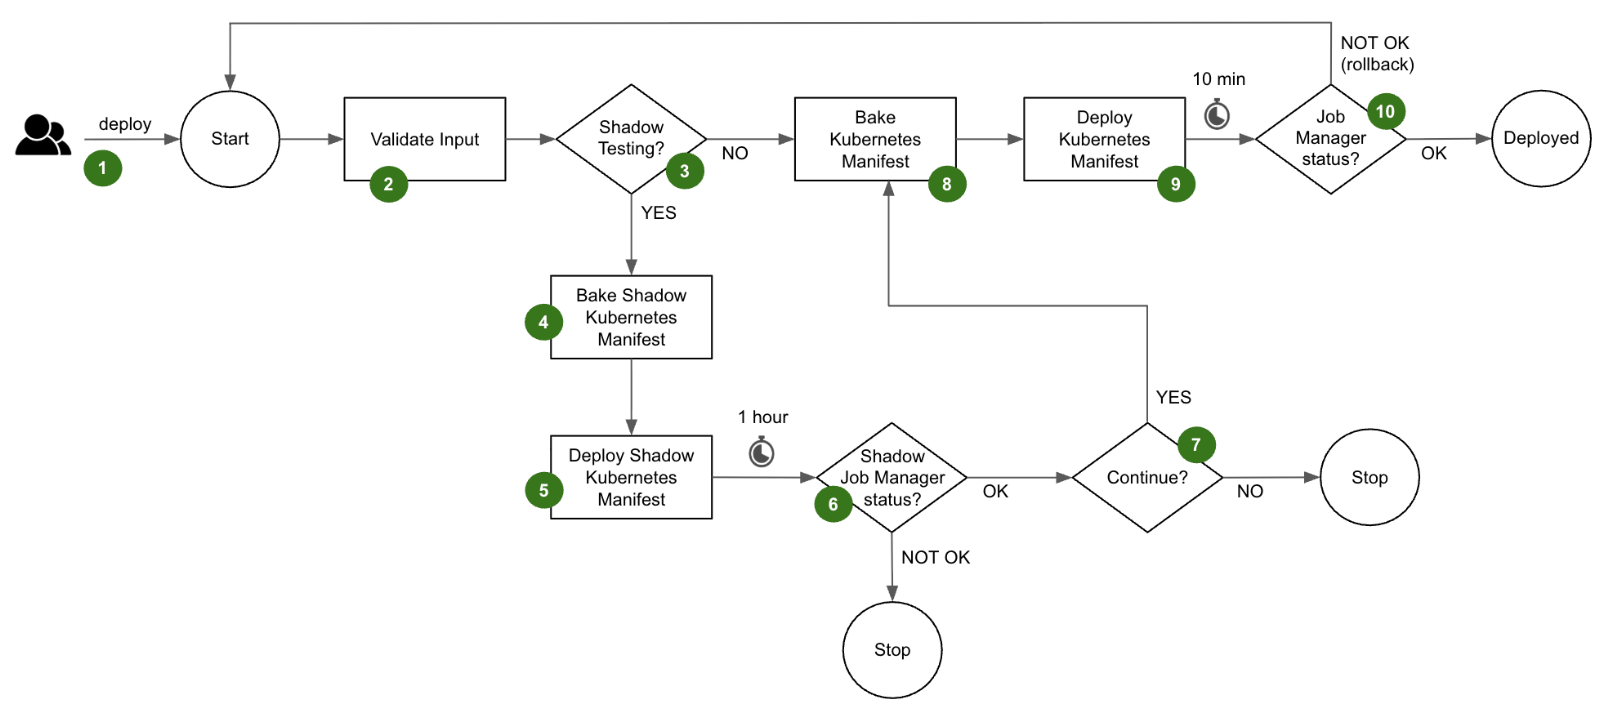
SpellVault’s evolution: Beyond LLM apps, towards the agentic future

Post Syndicated from Grab Tech original https://engineering.grab.com/spellvault-evolution-beyond-llm

Introduction

At Grab, innovation isn’t just about building new features; it’s about evolving our platforms to meet the changing needs of our users and the broader technological landscape. SpellVault, our internal AI platform, exemplifies this philosophy. When SpellVault was first launched, our vision was straightforward: empower everyone at Grab to effortlessly build and manage AI-powered apps without the need for coding. Built on the principles of Retrieval-Augmented Generation (RAG) and enhanced by plugin support, SpellVault rapidly evolved into a powerful productivity engine for the organization, enabling the creation of thousands of apps that drive automation, foster experimentation, and support production use cases.

As the AI landscape has evolved, SpellVault has grown alongside it. Initially launched as a straightforward no-code app builder for Large Language Models (LLMs), it has now evolved into a cutting-edge platform that embraces the agentic future—a future where AI goes beyond generating responses to reasoning, acting, and dynamically adapting through the use of tools and contextual understanding.

This article outlines SpellVault’s journey towards an agentic future and how we empower users to build AI Agents that are smarter, more adaptable, and ready for the future.

A no-code platform for building LLM apps

SpellVault was founded with a clear mission: to democratize access to AI for everyone at Grab, regardless of their technical expertise. Initially launched as a no-code LLM app builder, the platform was built on a foundation of RAG pipelines and basic plugin support.

Early on, we recognized that the true potential of AI apps extends beyond the capabilities of language models alone. Their real value lies in the ability to seamlessly interact with external systems and diverse data sources. This insight drove our commitment to minimizing barriers and ensuring users could access data from various sources with ease. From the very beginning, we centered our efforts on three key focus areas:

Comprehensive RAG solution with useful integrations

From the start, the SpellVault team prioritized enabling users to enhance their LLM apps with data through RAG. Rather than solely relying on the LLM’s internal information, we wanted the apps to ground their responses in up-to-date, contextually relevant, and factual information. SpellVault has built-in integrations with knowledge sources such as Wikis, Google Docs, as well as plain text and PDF uploads. These capabilities empower users to build assistants that reference relevant knowledge and provide more accurate, verifiable answers.

Plugins to fetch information on demand

To move beyond static knowledge retrieval, we needed a way for apps to act dynamically. This was made possible through SpellVault plugins—modular components that allow apps to interact with internal systems (e.g. service dashboards, incident trackers) and external APIs (e.g. search engines, weather data). Rather than being confined to their initial prompt and data, these plugins can fetch fresh information at runtime. From the available plugin types, users can create their own instances of plugins with custom settings, enabling highly specialized functionality tailored to their specific workflows. For instance, with SpellVault’s HTTP plugin, users can define custom endpoints and credentials, enabling their AI apps to make tailored HTTP calls during runtime. These custom plugins have become the backbone of many of our most impactful apps, empowering teams to seamlessly integrate SpellVault with their existing systems and processes.

Figure 1. SpellVault’s early architecture.

Making SpellVault accessible via common interfaces: Web, Slack, API

One of our primary goals was to make AI seamlessly accessible and useful within the tools users already use—whether it’s a browser or Slack. With SpellVault, users can make their AI apps in minutes and start using them via browser or Slack messaging immediately and intuitively, without requiring any additional setup. We also exposed APIs that enabled other internal services to integrate with SpellVault apps for a variety of use cases. This multi-channel approach ensured that SpellVault wasn’t just a standalone sandbox but a platform woven into existing tools and processes.

Users quickly adopted the platform, creating thousands of apps for internal productivity gains, automation, and even production use cases. The platform’s success validated our hypothesis that there was significant demand for democratized AI tools within the organization.

Figure 2. SpellVault’s web interface for LLM App configuration and chat.

Evolution over time

The AI landscape over the past few years has been defined by relentless change. New frameworks, execution paradigms, and standards have emerged in quick succession, each promising to make AI systems more powerful, more reliable, or more extensible. At Grab, we recognized that for SpellVault to stay relevant, it could not remain static. It needed to evolve in tandem with the ever-changing ecosystem, continuously incorporating valuable advancements while ensuring a seamless experience for our users.

This philosophy of continuous adaptation has guided SpellVault’s journey. From its early days as a simple RAG-powered app builder with a few plugins, the platform grew to support an extensive number of plugin types, richer execution models, and eventually a unified approach to tools. Each step was a response both to the needs of our users and to the shifting definition of what “building with AI” meant in practice. Rather than opting for a complete overhaul, SpellVault has embraced incremental advancements, ensuring that users can seamlessly benefit from new capabilities without disruption.

This approach to evolution has naturally positioned SpellVault to transition from a platform for LLM apps to one designed for AI agents. The following section delves into this transition in greater detail.

Expanding capabilities

Over time, we introduced numerous new capabilities to SpellVault, driven both by user feedback and our commitment to innovation and staying ahead of industry trends. For instance, we extended support for different plugin types, enabling integrations with tools like Slack and Kibana, and continuously added more integrations to enhance the platform’s versatility. We implemented auto-updates for users’ Knowledge Vaults, ensuring their data remained current. With more users building with the platform, ensuring the trustworthiness of responses generated by SpellVault apps became increasingly important. We included citation capability to mitigate some of that concern. Recognizing the need for more precise answers to mathematical problems, we developed a feature that enabled LLMs to solve such problems using Python runtime. Additionally, many users requested an automated way to trigger their LLM apps, which led to the creation of a Task Scheduler feature that allows LLMs to schedule actions based on natural language user input.

A significant milestone in SpellVault’s evolution was the introduction of “Workflow,” a drag-and-drop interface within the platform that empowered users to design deterministic workflows. These workflows enabled users to seamlessly combine various components from the SpellVault ecosystem—such as LLM calls, Python code execution, and Knowledge Vault lookups—in a predefined and structured manner. This enabled advanced use cases for many users.

Figure 3. Evolving tools landscape of SpellVault with increasing integrations.

Shifting the execution model

As SpellVault evolved, a fundamental shift took place in the way its apps were executed internally. We transitioned from our legacy executor system, which facilitated one-off information retrieval from the Knowledge Vault or user plugins, to a more advanced graph based executor. This empowered SpellVault’s app execution with nodes, edges, and states that supported branching, looping, and modularity. This laid the groundwork for more sophisticated agent behaviors, moving beyond the linear input-output paradigm.

This transformed all existing SpellVault apps into ‘Reasoning and Acting’ agents, better known as ReAct agents – a “one size fits many” solution that significantly enhanced the capabilities of these apps. By enabling them to leverage the Knowledge Vault and plugins in a more agentic and dynamic manner, the ReAct agent framework allowed apps to perform more complex tasks while seamlessly preserving their existing functionality, ensuring no disruption to their behavior.

In addition, the internal decoupling of the executor and prompt engineering components enabled us to design multiple execution pathways with ease. This allowed us to provide generic Deep Research capability to any SpellVault app via a simple UI checkbox, as well as sophisticated internal workflows that cater to high-ROI complex use cases like on-call alert analysis. The Deep Research capability came with SpellVault’s ability to search across internal information repositories (e.g., Slack messages, Wiki, Jira) within Grab, as well as searching online for relevant information.

Figure 4. SpellVault’s evolved architecture with more dynamic context gathering and advanced interaction modes.

Towards an agentic framework

Over time, several capabilities were added to SpellVault, including features like Python code execution and internal repository search. Initially, these functionalities were integrated directly into the core PromptBuilder class. For users, these features were primarily accessible through simple checkboxes in the user interface. As SpellVault gradually transitioned towards giving more agency to user-crafted apps, we recognized that these capabilities should instead be positioned as “Tools” for LLMs to use with greater autonomy, similar to how ReAct agent–backed apps have been using SpellVault’s user plugins. We also understood that this shift could bring a clearer mental model for users where they were no longer simply toggling features but creating AI agents with access to a defined set of tools. The agents could then decide when and how to use those tools intelligently to accomplish tasks, making the overall experience more natural and intuitive.

This recognition led to the consolidation of these scattered capabilities into a unified framework called “Native Tools.” These Native Tools, along with SpellVault’s existing user plugins—rebranded as “Community Built Tools”—formed a comprehensive collection of tools that LLMs could dynamically invoke at runtime. Despite being grouped under the same umbrella, a key distinction was maintained: Native Tools required no user-specific configuration (e.g., performing internet searches), whereas Community Built Tools were custom, user-configured entities (e.g., invoking specific HTTP endpoints) created from available plugin types, often requiring credentials or other personalized settings.

This consolidation of capabilities under a unified Tools abstraction and enabling SpellVault apps to invoke them with greater autonomy marked a pivotal milestone in the platform’s evolution. It meaningfully shifted SpellVault toward making agentic behavior more natural, discoverable, and extensible for every app.

Figure 5. SpellVault’s Unified Tools housing both Native Tools and Community Built Tools.

SpellVault as an MCP service

As we streamlined SpellVault’s internal capabilities into a unified tools framework, we also turned our focus outward to align with industry standards. The growing adoption of the Model Context Protocol (MCP) presented an opportunity for agents and clients to seamlessly interact without requiring custom integrations. To remain at the forefront of innovation, we adapted SpellVault to function as an MCP service, enabling it to actively participate in this evolving ecosystem. This extension brought two key advancements:

  • SpellVault apps as MCP tools: Each app created in SpellVault can now be exposed through the MCP protocol. This allows other agents or MCP-compatible clients, such as IDEs or external orchestration frameworks, to treat a SpellVault app as a callable tool. Instead of living only inside our web user interface or Slack interface, these apps become accessible building blocks that other systems can invoke dynamically.

  • RAG as an MCP tool: We extended the same idea to our Knowledge Vaults. Through MCP, external clients can search, retrieve, and even add information to Vaults. This effectively turns SpellVault’s RAG pipeline into an MCP-native service, making contextual grounding available to agents beyond SpellVault itself.

While building the SpellVault MCP Server, we also created TinyMCP – a lightweight open-source Python library that adds MCP capabilities to an existing FastAPI app as just another router, instead of mounting a separate app.

By exposing both apps and RAG through MCP, we shifted SpellVault from being a self-contained platform to becoming an interoperable service provider in the agentic ecosystem. Users still benefit from the no-code simplicity inside SpellVault. However, the output of their work, apps, and knowledge, are now usable by other agents and tools outside of it.

Conclusion

SpellVault’s evolution shows how a platform can adapt with the AI landscape while staying true to its original mission of making powerful technology accessible to everyone. What began as a no-code builder for LLM apps has steadily expanded into an agentic platform – one where apps can act with more intelligence, agency, and context and interact with the systems around them.

This progress wasn’t the result of a single breakthrough, but of steady, incremental improvements that introduced new capabilities while preserving ease of use. By layering in these advancements thoughtfully but boldly, SpellVault has managed to support more sophisticated agentic behaviors without compromising its original goal of democratizing AI at Grab.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
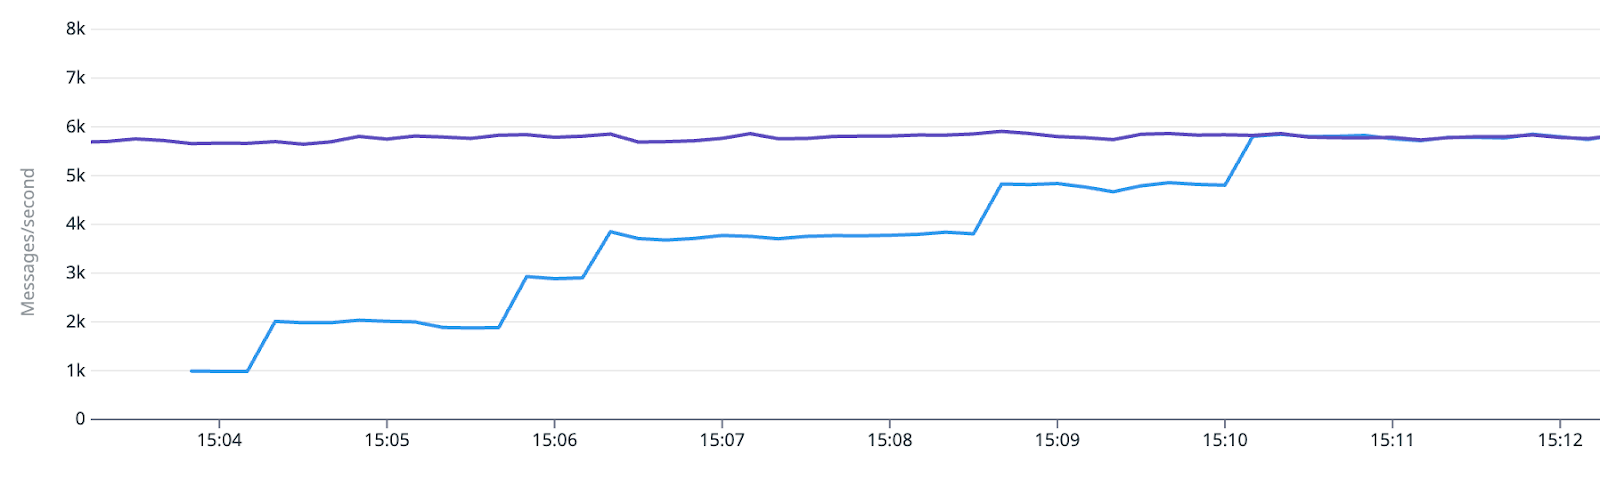
How We Built a Custom Vision LLM to Improve Document Processing at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/custom-vision-llm-at-grab

Introduction

In the world of digital services, accurate extraction of information from user-submitted documents such as identification (ID) cards, driver’s licenses, and registration certificates is a critical first step for processes like electronic know-your-customer (eKYC). This task is especially challenging in Southeast Asia (SEA) due to the diversity of languages and document formats.

We began this journey to address the limitations of traditional Optical Character Recognition (OCR) systems, which struggled with the variety of document templates it had to process. While powerful proprietary Large Language Models (LLMs) were an option, they often fell short in understanding SEA languages, produced errors, hallucinations, and had high latency. On the other hand, open-sourced Vision LLMs were more efficient but not accurate enough for production.

This prompted us to fine-tune and ultimately develop a lightweight, specialized Vision LLM from the ground up. This blog is our account of the entire process.

Figure 1: Simplified overview of how Vision LLM works.

Background

What is a Vision LLM?

You’ve likely heard of LLMs that process text. You give the LLM a text prompt, and it responds with a text output. A Vision LLM takes this a step further by allowing the model to understand images. The basic architecture involves three key components:

  • Image encoder: This component ‘looks’ at an image and converts it into a numerical (vectorized) format.
  • Vision-language projector: It acts as a translator, converting the image’s numerical format into a representation that the language model can understand.
  • Language model: The familiar text-based model that processes the combined image and text input to generate a final text output.
Figure 2: Vision LLM basic architecture.

Choosing our base Vision LLM model

We evaluated a range of LLMs capable of performing OCR and Key Information Extraction (KIE). Our exploration of open-source options—including Qwen2VL, miniCPM, Llama3.2 Vision, Pixtral 12B, GOT-OCR2.0, and NVLM 1.0—led us to select Qwen2-VL 2B as our base multimodal LLM. This decision was driven by several critical factors:

  • Efficient size: It is small enough for full fine-tuning on GPUs with limited VRAM resources.
  • SEA language support: Its tokenizer is efficient for languages like Thai and Vietnamese, indicating decent native vocabulary coverage.
  • Dynamic resolution: Unlike models that require fixed-size image inputs, Qwen2-VL can process images in their native resolution. This is crucial for OCR tasks as it prevents the distortion of text characters that can happen when images are resized or cropped.

We benchmarked Qwen2VL and miniCPM on Grab’s dataset. Our initial findings showed low accuracy, mainly due to the limited coverage of SEA languages. This motivated us to fine-tune the model to improve OCR and KIE accuracy. Training the LLM can be a very data-intensive and GPU resource-intensive process. Due to this, we had to address these two concerns before progressing further:

  • Data: How do we use open source and internal data effectively to train the model?
  • Model: How do we customize the model to reduce latency but keep high accuracy?

Training dataset generation

Synthetic OCR dataset

We extracted the SEA languages text content from a large online text corpus—Common Crawl (internet dataset). Then, we used an in-house synthetic data pipeline to generate text images by rendering SEA text contents in various fonts, backgrounds and augmentations.

The dataset contains text in Bahasa Indonesia, Thai, Vietnamese, and English. Each image has a paragraph of random sentences extracted from the dataset as shown in Figure 3.

Figure 3: Two synthetic sample images in Thai language used for model training.

Documint: AI-powered, auto-labelling framework

Our experiments showed that applying document detection and orientation correction significantly improves OCR and information extraction. Now that we have an OCR dataset, we needed to generate a pre-processing dataset to further improve model training.

Documint is an internal platform developed by our team that creates an auto‑labelling and pre‑processing framework for document understanding. It prepares high‑quality, labelled datasets. Documint utilizes various submodules to effectively execute the full OCR and KIE task. We then used a pipeline with the large amount of Grab collected cards and documents to extract training labels. The data was further refined by a human reviewer to achieve high label accuracy.

Documint has four main modules:

  • Detection module: Detect the region from the full picture.
  • Orientation module: Gives correction angle (e.g. if document is upside down, 180 degrees).
  • OCR module: Returns text values in unstructured format.
  • KIE module: Returns JSON values from unstructured text.
Figure 4: Pipeline overview of Documint.

Experimentation

Phase 1: The LoRA experiment

Our first attempt in fine-tuning a Vision LLM involved fine-tuning an open-source model Qwen2VL, using a technique called Low-Rank Adaptation (LoRA). LoRA is efficient because it allows lightweight updates to the model’s parameters, minimizing the need for extensive computational resources.

We trained the model on our curated document data, which included various document templates in multiple languages. The performance was promising for documents with Latin scripts. Our experiment of LoRA fine-tuned Qwen2VL-2B achieved high field-level of accuracy for Indonesian documents.

However, the fine-tuned model still struggled with:

  • Documents containing non-Latin scripts like Thai and Vietnamese.
  • Unstructured layouts with small, dense text.

Phase 2: The power of full fine-tuning

Our experiments revealed a key limitation. While open-source Vision LLMs often have extensive multi-lingual corpus coverage for the LLM decoder’s pre-training, they lack visual text in SEA languages during vision encoder and joint training. This insight drove our decision to pursue full parameter fine-tuning for optimal results.

Drawing from the Large Language and Vision Assistant (LLAVA) methodology, we implemented a two-stage training approach illustrated in Figure 5.

Figure 5: From left to right—two-stage training process.

Stage 1 – Continual pre-training: We first trained the vision components of the model using synthetic OCR datasets that we created for Bahasa Indonesia, Thai, Vietnamese, and English. This helps the model to learn the unique visual patterns of SEA scripts.

Stage 2 – Full-parameter fine-tuning: We then fine-tuned the entire model—vision encoder, projector, and language model—using our task-specific document data.

Results:

Table 1: OCR Field level accuracy between the baseline and Qwen2-VL 2B model. (pp: percentage points).

The fully fine-tuned Qwen2-VL 2B model delivered significant improvement, especially on documents that the LoRA model struggled with.

  • Thai document accuracy increased +70pp from baseline.
  • Vietnamese document accuracy rose +40pp from baseline.

Phase 3: Building a lightweight 1B model from scratch

While the Qwen2VL-2B model was a success, the full fine-tuning pushed the limits of GPUs. To optimize resources used and to create a model perfectly tailored to our needs, we decided to build a lightweight Vision LLM (~1B parameters) from scratch.

Our strategy was to combine the best parts of all models:

  • We took the powerful vision encoder from the larger Qwen2-VL 2B model.
  • We paired it with the compact and efficient language decoder from the Qwen2.5 0.5B model.
  • We connected them with an adjusted projector layer to ensure they could work together seamlessly.

This created a custom ~1B parameter Vision LLM optimized for training and deployment.

Four stages in training our custom model

We trained our new model using a comprehensive four-stage process as shown in Figure 6.

Figure 6: From left to right— four stages of model training.

Stage 1 – Projector alignment: The first step was to train the new projector layer to ensure the vision encoder and language decoder could communicate effectively.

Stage 2 – Vision tower enhancement: We then trained the vision encoder on a vast and diverse set of public multimodal datasets, covering tasks like visual Q&A, general OCR, and image captioning to improve its foundational visual understanding.

Stage 3 – Language-specific visual training: We trained the model on two types of synthetic OCR data. Without this stage, performance on non-Latin documents dropped by as much as 10%.

Stage 4 – Task-centric fine-tuning: Lastly, we performed full-parameter fine-tuning on our custom 1B model using our curated document dataset.

The final results are as follow:

Accuracy:

  • It achieved performance comparable to the larger 2B model, staying within a 3pp accuracy gap across most document types. The model also maintained strong generalization when trained on quality-augmented datasets.

Latency:

  • The latency of our model far outperforms the 2B model, as well as traditional OCR models, as well as external APIs like chatGPT or Gemini. One of the biggest weaknesses we identified with external APIs was the P99 latency, which can easily be 3 to 4x the P50 latency, which would not be acceptable for Grab’s large scale rollouts.
Table 2: Performance comparison between Qwen2-VL 2B and 1B sized Vision LLM.

Key takeaways

Our work demonstrates that strategic training with high-quality data enables smaller, specialized models to achieve remarkable efficiency and effectiveness. Here are the critical insights from our extensive experiments:

  • Full fine-tuning is superior: For specialized, non-Latin script domains, full-parameter fine-tuning dramatically outperforms LoRA.
  • Lightweight models are effective: A smaller model (~1B) built from scratch and trained comprehensively can achieve near state-of-the-art results, validating the custom architecture.
  • Base model matters: Starting with a base model that has native support for your target languages is crucial for success.
  • Data is king: Meticulous dataset preprocessing and augmentation plays a critical role in achieving consistent and accurate results.
  • Native resolution is a game changer: A model that can handle dynamic image resolutions preserves text integrity, dramatically improves OCR capabilities.

Our journey demonstrates that specialized Vision LLMs can effectively replace traditional OCR pipelines with a single, unified, highly accurate model—opening new possibilities for document processing at scale.

Table 3: Comparison of model types .

What’s next?

As we continue to enhance our Vision LLM capabilities, exciting developments are underway:

  • Smarter, more adaptable models: We’re developing Chain of Thought-based OCR and KIE models to strengthen generalisation capabilities and tackle even more diverse document scenarios.

  • Expanding across Southeast Asia: We’re extending support to all Grab markets, bringing our advanced document processing to Myanmar, Cambodia, and beyond.

References

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
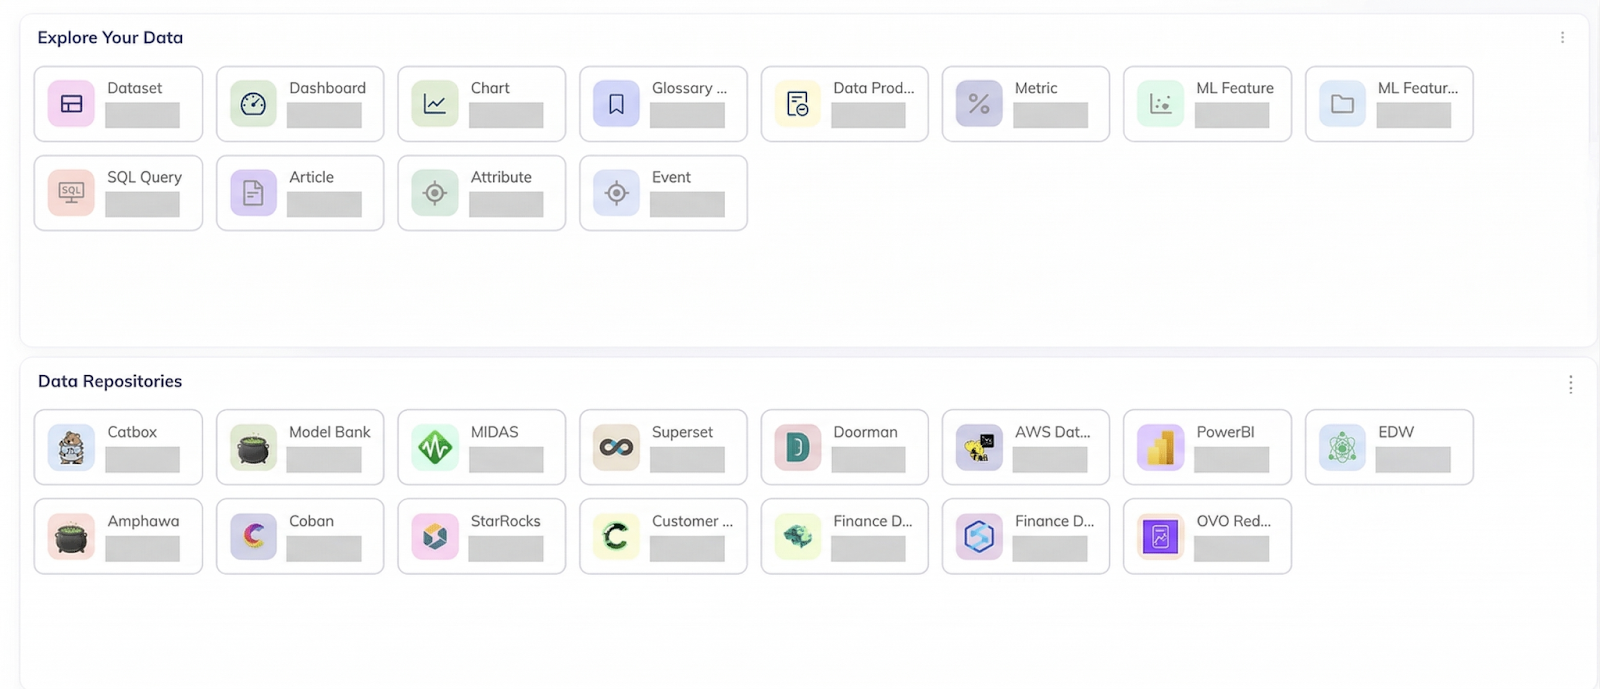
Machine-learning predictive autoscaling for Flink

Post Syndicated from Grab Tech original https://engineering.grab.com/ml-predictive-autoscaling-for-flink

Introduction

As Grab transitions to derive more valuable insights from our wealth of operational data, we are witnessing a steep increase in stream-processing applications. Over the past year, the number of Flink applications grew 2.5 times, driven by interest in real-time stream processing and the improved accessibility of developing such applications with Flink SQL. At this scale, it has become crucial for the internal Flink platform team to provide a cost-effective and self-service offering that supports users of diverse backgrounds.

Flink at Grab is deployed in application mode, each pipeline has its own isolated resources for JobManager and TaskManager. Flink pipeline creators control both application logic and deployment configuration that affect throughput and performance, including OSS configurations:

  • Number of TaskManagers and task slots per TaskManager
  • CPU cores per TaskManager
  • Memory per TaskManager

As pipeline creation has become more accessible, users of different backgrounds (analyst, data scientist, engineers, etc.) often struggle to choose a set of configurations that work for their applications. Many go through a long process of trial and error and still end up over-provisioning their applications, leading to huge resource waste. Moreover, pipeline behavior changes over time due to changes in application logic or data pattern, invalidating previous efforts in tuning and causing users to repeat the exercise.

In this article, we focus on addressing the challenge of efficient CPU provisioning for TaskManagers, as CPU constraints are a common bottleneck in our clusters. Our solution specifically targets Flink applications sourcing data from our message bus system (eg. Kafka, Change Data Capture Streams, DynamoDB Streams) , which represents the majority of our use cases. These workloads offer significant opportunities for cost savings due to their clear seasonal patterns, making them an ideal starting point for optimising autoscaling strategies.

Limits of reactive autoscaling

Our initial reactive setup

Our first automated solution relied on Flink’s Adaptive Scheduler in Reactive Mode. In this mode, each Flink application is deployed as its own individual Flink cluster running a dedicated job. The cluster greedily uses all available TaskManagers and scales its job parallelism accordingly. Running on Kubernetes, the cluster relies on Horizon Pod Autoscaler (HPA) to scale the number of TaskManager pods based on metrics such as CPU usage or custom metrics such as the pipeline’s consumer latency. While this solution was helpful initially, we quickly observed multiple issues with it.
It is important to note that while the below issues can be solved by fine-tuning, it is a tedious trial and error effort that only works for specific applications, requiring users to repeat the process for every pipeline they own.

Restart spike: root cause of many issues

When autoscaling a Flink pipeline, the job restarts from the last checkpoint. This triggers an immediate spike in load, as the pipeline must reprocess records from the period between the last checkpoint and job restart, along with any new records that were backlogged at the source during the downtime. As a result, CPU usage and P99 consumer latency typically spikes after scaling events, for example, at 00:05 and 00:55, as shown in Figure 1. These spikes occur even though there is no change in source topic throughput. In this case, CPU usage surges from 0.5 cores to near provision limit of 2.5 cores, while consumer latency temporarily spiked from sub-second levels to as high as three minutes.

Figure 1: CPU usage and consumer latency spike after a pipeline restart.

Reactive spiral and fluctuation

Typically, HPA scales on metrics such as CPU usage, consumer latency, or backpressure crossing a defined threshold. The challenge arises if these thresholds are misconfigured. The HPA’s reactive nature, when combined with restart spikes, can become detrimental to your Flink application. It piles additional load onto a system that’s already degrading, further amplifying the problem.

Figure 2: A reactive scaling incident that demonstrates scaling fluctuations and restarts.

Figure 2 provides us a case study of reactive spiral and fluctuation, assuming we are having a pipeline that consumes a Kafka topic of 300 partitions:

  • 07:00: As the source topic throughput increases, the P99 consumer latency rises due to insufficient processing power.
  • 07:15: Reactive scaling is triggered, resulting in a scale out event. This is reflected in the increased TaskManager and task slot count. The pipeline continues to operate, as there is no increase in restart count.
  • 07:30: As the P99 consumer latency remains high, reactive scaling continues to scale out incrementally. The records in rate by task rises rapidly as the pipeline reprocesses data from the checkpoint. During this period, the pipeline repeatedly restarts CPU usage drops significantly, and P99 consumer latency spikes to nearly one hour. This marks the onset of a spiral failure.
  • 08:00: Reactive scaling reaches its upper limit of 300 slots, corresponding to the number of partitions in the source topic. This halts the spiral effect as it cannot scale out any further. Without disruption from autoscaling restart, the pipeline begins to process the backlog since the last successful checkpoint, as observed by the significant increase in records in rate by task. As the pipeline catches up, it eventually stabilizes, and the P99 consumer latency returns to normal levels.
  • 08:30 – 10:15: The P99 consumer latency returns to normal levels, below the threshold. Reactive scaling triggers scale-in events despite the source topic throughput continuing to trend upward. During these scale-in events, P99 latency fluctuates, occasionally spiking up to 15 minutes. However, these fluctuations are not severe enough to prevent the repeated scale in process.
  • 10:15: The P99 consumer latency rises again, triggering a scale-out event back to the upper limit of 300 slots.
  • 11:15-11:45: Despite the source topic throughput maintaining an upward trend, the pipeline undergoes multiple scale-in events in quick succession, encounters latency issues due to reprocessing data from checkpoints, and scales out again shortly after. This is an example of fluctuation after scaling in, resulting in 6 restarts within a 30 minutes window.

Limited parallelism constraints

Even with HPA, we frequently encounter a bottleneck when trying to scale our applications’ throughput. This is primarily because some of our connectors, most notably the Kafka connector, don’t inherently support dynamic parallelism changes.
Kafka topics, by design, have a fixed number of partitions. This directly limits the number of parallel consumers we can run. Consequently, once we reach this maximum parallelism for our consumers, we often have to scale up resources, for example, increase memory/CPU per instance instead of scaling out (adding more instances).

Predictive Resource Advisor

Assumptions and hypothesis

To tackle the issue of reactive spirals and fluctuations, the new solution should have the following characteristics:

  • Vertical scaling: To tackle the issue of limited parallelism with our dependencies, we should be looking at vertical instead of horizontal scaling.
  • Predictive: Adjust CPU to scale up or down before demand spikes or dips occur, ensuring the system is prepared for changes in workload. This prevents artificial workload increases caused by processing backlogs on top of actual workload increase, further straining the system.
  • Deterministic: The CPU configuration must be precisely calculated based on the workload demand, ensuring predictable and consistent resource allocation. For a given workload, the calculated CPU value should remain the same every time, eliminating variability and uncertainty in scaling decisions.
  • Accurate: Determine the optimal CPU configuration required to handle workload demand in a single, precise calculation, avoiding the inefficiencies of multi-step, trial-and-error tuning.

Key observations

Our solution is conceptualized based on key observations of our Flink applications:

  1. The CPU usage of Flink applications is primarily driven by the input load.
  2. The input load of our Flink applications can be accurately forecasted using time-series forecasting techniques.
  3. Time-based autoscaling that relies solely on historical CPU usage is not robust enough to adapt to evolving workloads. This approach also carries the risk of a negative self-amplifying feedback loop: each autoscaling restart causes a CPU usage spike (as illustrated in Figure 1), which, if anomalies are not properly handled, inflates subsequent CPU calculations.

Model formulation

We then formulate the relationship between CPU usage and input load using a regression model to provide a mathematical framework for predicting CPU requirements based on workload patterns, expressed as:

Ct = f(xt)

In this equation:

  • Ct represents the CPU required at a specific point in time.
  • xt represents the input workload at the corresponding point in time.
  • f() represents the regression function that maps the input load to the required CPU capacity.

Input load, represented by Kafka source topic throughput in our case, is chosen as the independent variable xt because it reflects true business demand and is entirely independent of Flink consumers. This metric is influenced solely by the business logic of upstream producers and remains unaffected by any changes or behaviors in the Flink consumer pipeline.

Proposed solution

Our predictive autoscaler operates through four key stages as shown in Figure 3.

Figure 3: The predictive autoscaling system operates through four key stages.

Stage 1: Workload forecast model

The workload forecast model is a time-series forecasting model trained on actual workload data, specifically source topic throughput from our Kafka cluster (1). This approach is particularly effective as our workload exhibits seasonal patterns. While historical data could be directly used as input for CPU prediction, time-series forecasting offers a more robust solution by enabling the model to account for organic traffic growth over time. Through periodic retraining, the model adapts to evolving workload trends, ensuring more accurate and reliable predictions for resource provisioning.

Stage 2: Resource prediction model

This follows the regression-based model Ct = f(xt) defined earlier. We use the same source topic throughput from our Kafka cluster (2a) as input feature xt, and the Flink application’s Kubernetes CPU usage metric (2b) as output label Ct for model training. To ensure clean and representative data for model training, we collect CPU usage metrics under conditions that simulate infinite resource availability. We include data exclusively from periods of continuous and stable operation, as determined by latency, uptime, and restart metrics (2b), eliminating biases caused by hardware limitations or disruptions.

Stage 3: Workload forecasting

To prepare for autoscaling, we forecast the workload for the future t-hour window (3) using our trained time-series forecast model.

Stage 4: Predict CPU usage

The forecasted workload (3) is fed into the resource prediction model to estimate the CPU usage required to handle that workload. The predicted value is then refined using custom safety feature adjustments to account for variability and ensure stability. This adjusted prediction is passed to the custom autoscaler controller, which evaluates the current CPU configuration of the TaskManager deployment. If the adjusted predicted value differs from the existing CPU configuration, the controller initiates vertical scaling to update the TaskManager deployment accordingly.

Proof of concept and results

Experiment setup

To validate our hypothesis, we present a deep dive into one of our experiments. This pipeline features complex business logic, aggregates from multiple Kafka sources, with a checkpoint interval of one minute and a maximum consumer latency of five minutes.

We set up an experimental pipeline with configurations identical to the production pipeline (the control). Both applications sourced data from the same Kafka topics but sank data to alternative topics to maintain isolation. The Predictive Resource Advisor was enabled on the experimental pipeline, while the control pipeline operated with fixed CPU provisioning.

Results

Figure 4 demonstrates a strong correlation between CPU usage (yellow, green) and the total Kafka topics throughput. The variable CPU provisioning (blue) for the experimental pipeline is calculated by our autoscaler models, which were trained exclusively on data collected from the experiment pipeline. The CPU usage trend of the experimental pipeline closely mirrors that of the control pipeline and remains aligned with the Kafka throughput trend. However, the experimental pipeline’s CPU provisioning is dynamically adjusted to more closely match its actual CPU usage, whereas the control pipeline maintains a static CPU allocation (purple). This illustrates the model’s effectiveness in dynamically adjusting CPU allocation to meet variable workload demands.

Figure 4: CPU usage closely correlates with source throughput for both the experimental and control pipelines.

Without autoscaler enabled, the control pipeline experienced no disruptions and maintained latency (blue) consistently below one second, which is not visible in Figure 5. On the other hand, the experiment pipeline latency (red) experienced a highest recorded peak latency of just over four minutes during a single disruption window. Other latency spikes observed were comparable to or lower than the three minutes peak latency previously identified as part of the restart spike issue analysis. The varied durations and amplitudes of these spikes showed some correlation with the heavy Kafka topic throughput during those periods. Importantly, there were only nine autoscaling events throughout the day, resulting in nine restarts for the experiment pipeline.

Figure 5: Autoscaling impacts service-level agreement requirements through latency spikes during scaling events.

Outcome

The Predictive Resource Advisor solution has been successfully deployed across more than 50% of applicable production applications, specifically those consuming from Kafka topics and exhibiting seasonal workload patterns with some tolerance for disruptions. This implementation has delivered significant results across three key areas, stability, efficiency, and user experience.

Stability

With autoscaling becoming more predictable and controllable, our Flink applications experience fewer disruptions caused by autoscaling fluctuations. The machine learning and predictive capabilities of the solution also ensure that applications remain operational during periods of increased workload by automatically learning and adapting to organic growth trends and workload surges.

Efficiency

Applications powered by the Predictive Resource Advisor demonstrated significant improvements in CPU provisioning, aligning CPU configuration more closely with actual requirements, particularly during low traffic periods. As a result of this optimization, on average, these applications made approximately >35% savings in cloud infrastructure cost.

User experience

The solution has simplified the deployment process for users, allowing them to simply deploy Flink applications with default configurations. The Predictive Resource Advisor automatically collects data, trains autoscaling models, and applies configuration changes, thus eliminating the need for manual fine-tuning. This significantly enhances the user experience by streamlining pipeline maintenance and enabling self-service capabilities, such as effortless onboarding. It empowers users to explore and derive value from real-time features with minimal effort.

What’s next?

Our journey doesn’t stop here. We’re continuously working to enhance our predictive autoscaler, with the following key areas of focus:

  • Tackling memory configuration (Predictive Resource Advisor’s next frontier)
    Memory is critical yet often misconfigured that can lead to unrecoverable failures for example, OOMKilled. Our next major goal for the Predictive Resource Advisor is to take on memory tuning, completely removing the burden of complex memory configuration from our users and further empowering them.
  • Enhancing model accuracy
    To further improve the robustness of our predictions, we are actively exploring advanced techniques in input feature engineering and anomaly detection, especially for workloads exhibiting frequent bursting patterns. By refining these aspects, we aim to extend the applicability of our solution to a broader range of Flink applications, including those connected to diverse sources such as change data capture systems or batch-like, spiky workloads, such as the Flink applications powering our real-time data lake.
  • Streamlining model training
    We’re developing a more efficient model training workflow. A particularly exciting avenue we’re investigating is the use of pretrained time-series forecasting models based on large language model architectures.

References

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
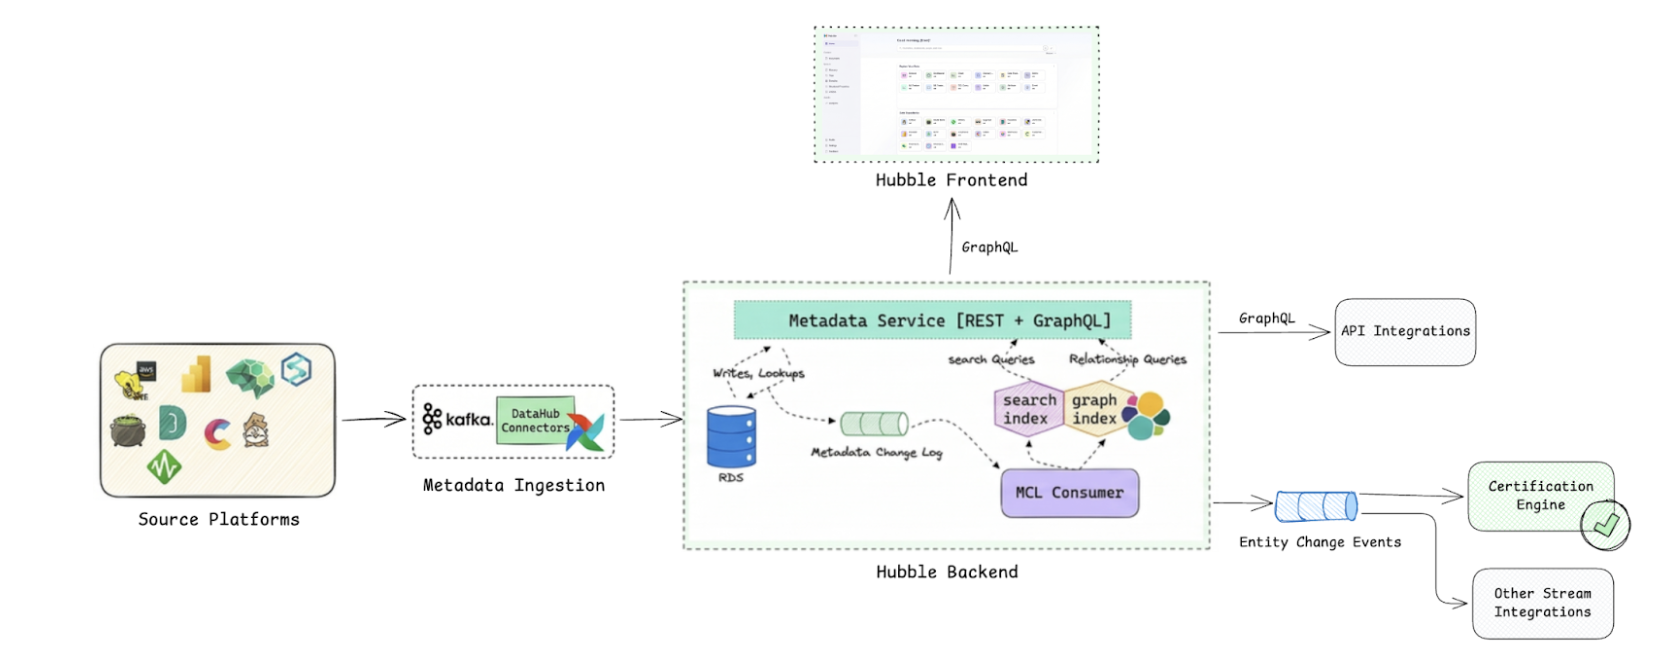
Modernising Grab’s model serving platform with NVIDIA Triton Inference Server

Post Syndicated from Grab Tech original https://engineering.grab.com/modernising-grab-model-serving-platform

Introduction

Catwalk is Grab’s machine learning (ML) model serving platform, designed to enable data scientists and engineers in deploying production-ready inference APIs. Currently, Catwalk powers hundreds of ML models and online deployments. To accommodate this growth, the platform has adapted to the rapidly evolving machine learning technology landscape. This involved progressively integrating support for multiple frameworks such as ONNX, PyTorch, TensorFlow, and vLLM. While this approach initially worked for a limited number of frameworks, it soon became unsustainable as maintaining various inference engines, ensuring backward compatibility, and managing deprecated legacy components (such as the ONNX server) introduced significant technical debt. Over time, this resulted in degraded platform performance: with increased latency, reduced throughput, and escalating costs. These issues began to impact users, as larger models could no longer be served efficiently or cost-effectively by legacy components. Recognising the need for change, the team revisited the platform’s design to address these challenges.

Evaluation and implementation

After evaluating other industry-leading model serving platforms and studying best practices, we decided to conduct an in-depth analysis of NVIDIA Triton. Triton offers significant advantages as an inference engine, including:

  • Multi-framework support: Compatibility with major ML frameworks, including ONNX, PyTorch, and TensorFlow, ensuring versatility and broad applicability.

  • Unified inference interface: Provides a single, consistent API for various ML frameworks, simplifying user interaction and reducing overhead when switching between models or frameworks.

  • Hardware optimisation: Optimised for NVIDIA GPUs, Triton delivers strong performance on CPU-only environments and specialised instances like AWS Inferentia.

  • Up-to-date support: Continuously updated by upstream to support the latest optimisation and features from upstream ML frameworks, ensuring access to cutting-edge capabilities.

  • Advanced inference features: Includes capabilities like dynamic batching and model ensembling (model pipelining), which enhances throughput and efficiency for complex ML workflows.

Our extensive benchmarking demonstrated that NVIDIA Triton delivers substantial enhancements in both performance and service stability compared to our existing solutions.

We are now working towards consolidating the various inference engines we manage into a unified, all-in-one Triton engine, beginning with ONNX adoption as the first phase of implementation.

In this blog, we aim to share our journey of adopting Triton. From initial benchmarking results on one of Grab’s core models facing performance challenges, to the development of the “Triton manager”, a component designed to integrate Triton into our platform seamlessly and with minimal user disruption. Ultimately, more than 50% of online deployments were successfully migrated to Triton, with some of our critical systems achieving a 50% improvement in tail latency.

Exploratory benchmark results

We conducted rigorous testing of Triton against our existing ONNX server under varying levels of request traffic.

Table 1: Benchmark results of Triton against Catwalk ONNX server.

During testing with a transformer-based model, Triton demonstrated the ability to handle at least 5 times the traffic while maintaining excellent latency. Additionally, its performance was further enhanced with features like batching enabled, and there is potential for even greater optimisation by converting the model to TensorRT, leveraging GPU support.

Through profiling, we learned that a handful of ONNX Runtime knobs have an outsized impact on throughput. One low-effort, high-return tweak is to set the intra-op thread count to match the number of physical CPU cores. In most cases, this single change yields a healthy performance lift, sparing us from time-consuming, model-by-model micro-optimisation.

Adopting Triton at scale

While the benchmark results clearly demonstrate Triton’s advantages, the primary challenge was ensuring a seamless migration, ideally with minimal user reactions. Given the high frequency of migrations within our company, even exceptional performance improvements are often insufficient to fully motivate internal users to adopt new systems. From our point of view, a successful migration required:

  • Maintaining API compatibility with existing systems.
  • Ensuring zero-downtime.
  • Preserving all existing functionality while adding new capabilities.
  • Minimising disruption to downstream services and users.

To streamline the migration process, we opted to manage it centrally within our platform, rather than relying on individual users to address the details themselves.

We landed on the idea of offering Triton to our users as a drop-in replacement for the old server, with the help of a new component, “Triton manager”. The Triton manager is a critical component that glues Triton to the Catwalk ecosystem. It consists of two major components: Triton server manager and Triton proxy.

Triton server manager is designed as the entry point of our Catwalk Triton. It downloads the model from remote storage, runs verification on the model files, prepares per-model configurations based on users’ customisation, and lastly it launches the Triton server. It also periodically checks the server’s health and provides observability overlooking the server’s status.

Triton proxy provides backward compatibility to the existing clients. It hosts endpoints that translate requests from the older API and forward them to the Triton server. The proxy layer plays a crucial role in facilitating a seamless transition from our legacy servers, eliminating the need for user code changes. The conversion logic is designed to prioritise performance, ensuring minimal overhead. Extensive benchmarks were conducted during development to validate and optimise its efficiency.

Figure 1: High-level architecture for Triton Inference Server (TIS) deployment at Catwalk.

Finally, a special mode in the Triton server manager is implemented to allow the Triton Inference Server (TIS) to be backward compatible with the command line interface of the existing ONNX runtime server used in Catwalk.

We plan to enhance the Triton Manager to ensure backward compatibility with other ML frameworks, as part of our efforts to onboard additional frameworks seamlessly.

Rollout result

Within just 10 days of Triton’s availability, we successfully rolled it out to over 50% of our online model deployments. Thanks to rigorous testing for backward compatibility, the rollout was seamless, with most users unaware of the transition while benefiting from the improved performance.

Triton’s impacts on critical models

Figure 2: Latency before and after rollout in ms. Blue line: XGBoost-based model. Orange line: transformer-based model. Solid line: average. Dashed line: p99

We’ve observed significant performance improvements in our business-critical models that have high demands for stability. Latency improvements were consistently observed in all models, especially in the models that suffered from highly volatile request traffic. For some larger transformer models, the p90 latency decreased dramatically from 120ms to 20ms, and the average latency remained steady at 4ms. Smaller XGBoost models maintained their average latency at 2ms across regions.

Figure 3: Number of pods, before (blue line) and after (purple line) rollout in another model.

Triton has delivered significant cost savings for certain models, with some achieving over 90% reductions due to its advanced optimisations. These improvements have come alongside enhanced performance and reliability.

It is worth noting that Triton was initially rolled out with limited capabilities to prioritise backward compatibility and ensure a seamless migration. However, we’ve noticed that higher tail latency still remains an issue when facing request spikes for larger models in production. To address this, we are working on enabling batching through Triton to minimise tail latency during traffic surges. This effort will involve close collaboration with model owners to optimise the capacity of each Triton instance further.

Early cost impact of the migration

To gauge the financial upside of migrating to Triton, we took a snapshot of 11 production ML services that had already completed the migration. For every ML service, we compared its infrastructure spend over the 14 days before the cut-over with the 14 days after.

Despite the staggered migration dates, the trend was uniform: average spend fell by ~ 20% across this small cohort within 14 days. As more models and applications migrate, we expect the absolute dollar savings to scale proportionally.

Takeaways

Initial results are aligned with our benchmarks for the Triton migration. With improved performance and cost reduction, we expect model owners to either upgrade their model sizes or allow for higher Queries Per Second (QPS). While making further progress with the overall Triton migration, the model serving platform team will continue to monitor cost differences and provide consultation to model owners who seek further optimisation for their deployments.

Another key takeaway is the painless migration of Triton for our internal users. Rather than asking internal users to make necessary code changes, our team dedicated significant time to providing Triton as a drop-in inference engine to minimise any inconvenience of migration.

Big appreciation to Shengwei Pang from the Geo team, Khai Hung Do, Nhat Minh Nguyen, and Siddharth Pandey from the Catwalk team, along with Richard Ryu from the PM team and Padarn George Wilson for the sponsorship.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
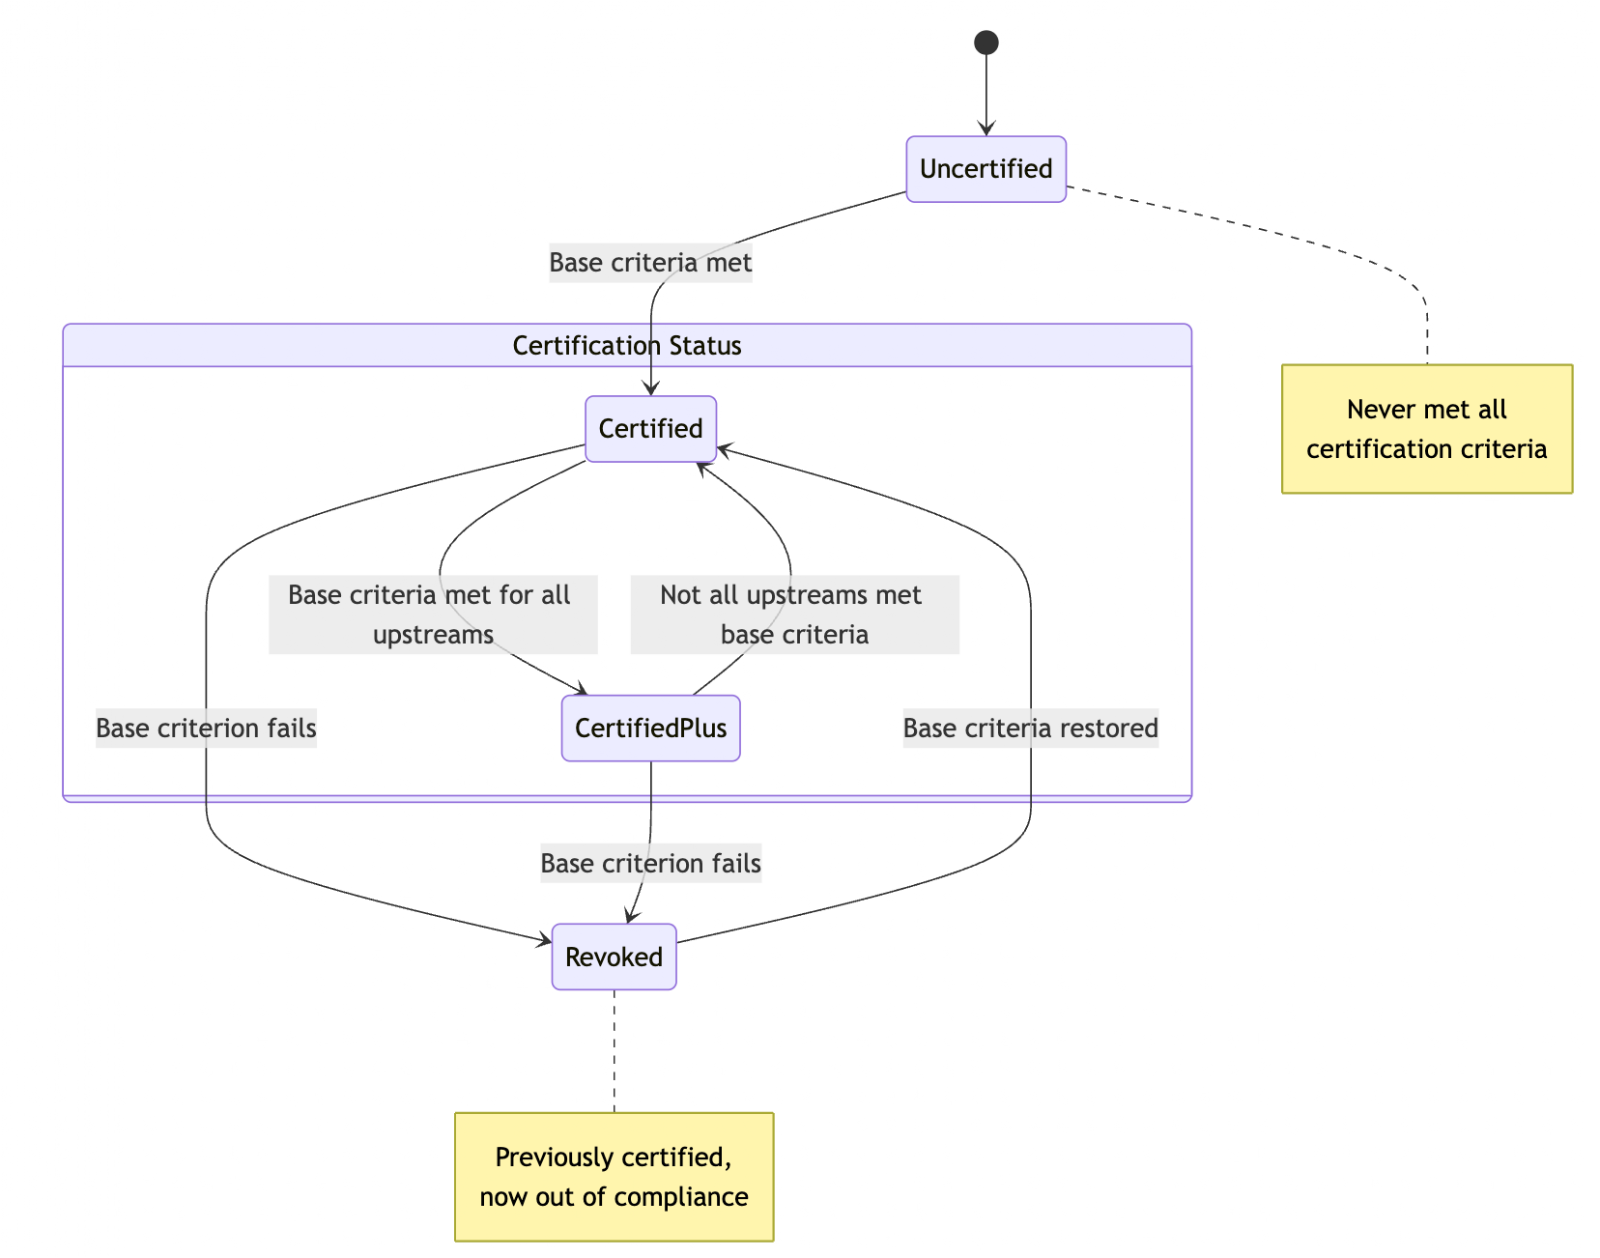
100X Faster: How We Supercharged Netflix Maestro’s Workflow Engine

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/100x-faster-how-we-supercharged-netflix-maestros-workflow-engine-028e9637f041

By Jun He, Yingyi Zhang, Ely Spears

TL;DR

We recently upgraded the Maestro engine to go beyond scalability and improved its performance by 100X! The overall overhead is reduced from seconds to milliseconds. We have updated the Maestro open source project with this improvement! Please visit the Maestro GitHub repository to get started. If you find it useful, please give us a star.

Introduction

In our previous blog post, we introduced Maestro as a horizontally scalable workflow orchestrator designed to manage large-scale Data/ML workflows at Netflix. Over the past two and a half years, Maestro has achieved its design goal and successfully supported massive workflows with hundreds of thousands of jobs, managing millions of executions daily. As the adoption of Maestro increases at Netflix, new use cases have emerged, driven by Netflix’s evolving business needs, such as Live, Ads, and Games. To meet these needs, some of the workflows are now scheduled on a sub-hourly basis. Additionally, Maestro is increasingly being used for low-latency use cases, such as ad hoc queries, beyond traditional daily or hourly scheduled ETL data pipeline use cases.

While Maestro excels in orchestrating various heterogeneous workflows and managing user end-to-end development experiences, users have experienced noticeable speedbumps (i.e. ten seconds overhead) from the Maestro engine during workflow executions and development, affecting overall efficiency and productivity. Although being fully scalable to support Netflix-scale use cases, the processing overhead from Maestro internal engine state transitions and lifecycle activities have become a bottleneck, particularly during development cycles. Users have expressed the need for a high performance workflow engine to support iterative development use cases.

To visualize our end users’ needs for the workflow orchestrator, we create a 5-layer structure graph shown below. Before the change, Maestro reached level 4 but faced challenges to satisfy the user’s needs in level 5. With the new engine design, Maestro is able to power the users to work with their highest capacity and spark joy for end users during their development over the Maestro.

Figure 1. A 5-layer structure showing needs for the workflow orchestrator
Figure 1. A 5-layer structure showing needs for the workflow orchestrator.

In this blog post, we will share our new engine details, explain our design trade-off decisions, and share learnings from this redesign work.

Architectural Evolution of Maestro

Before the change

To understand the improvements, we will first revisit the original architecture of Maestro to understand why the overhead is high. The system was divided into three main layers, as illustrated in the diagram below. In the sections that follow we will explain each layer and the role it played in our performance optimization.

Figure 2. The architecture diagram before the evolution.

Maestro API and Step Runtime Layer

This layer offers seamless integrations with other Netflix services (e.g., compute engines like Spark and Trino). Using Maestro, thousands of practitioners build production workflows using a paved path to access platform services . They can focus primarily on their business logic while relying on Maestro to manage the lifecycle of jobs and workflows plus the integration with data platform services and required integrations such as for authentication, monitoring and alerting. This layer functioned efficiently without introducing significant overhead.

Maestro Engine Layer

The Maestro engine serves several crucial functions:

  • Managing the lifecycle of workflows, their steps and maintaining their state machines
  • Supporting all user actions (e.g., start, restart, stop, pause) on workflow and step entities
  • Translating complex Maestro workflow graphs into parallel flows, where each flow is an array of sequentially chained flow tasks, translating every step into a flow task, and then executing transformed flows using the internal flow engine
  • Acting as a middle layer to maintain isolation between the Maestro step runtime layer and the underlying flow engine layer
  • Implementing required data access patterns and writing Maestro data into the database

In terms of speed, this layer had acceptable overhead but faced edge cases (e.g. a step might be concurrently executed by two workers at the same time, causing race conditions) due to lacking a strong guarantee from the internal flow engine and the external distributed job queue.

Maestro Internal Flow Engine Layer

The Maestro internal flow engine performed 2 primary functions:

  • Calling task’s execution functions at a given interval.
  • Starting the next tasks in an array of sequential task flows (not a graph), if applicable.

This foundational layer was based on Netflix OSS Conductor 2.x (deprecated since Apr 2021), which requires a dedicated set of separate database tables and distributed job queues.

The existing implementation of this layer introduces an impactful overhead (e.g. a few seconds to tens of seconds overall delays). The lack of strong guarantees (e.g. exactly once publishing) from this layer leads to race conditions which cause stuck jobs or lost executions.

Options to consider

We have evaluated three options to address those existing issues:

  • Option 1: Implement an internal flow engine optimized for Maestro specific use cases
  • Option 2: Upgrade Conductor library to 4.0, which addresses the overheads and offers other improvements and enhancements compared with Conductor 2.X.
  • Option 3: Use Temporal as the internal flow engine

One aspect that influenced our assessment of option two is that Conductor 2 provided a final callback capability in the state machine that was contributed specifically for Maestro’s use case to ensure database synchronization between the Conductor and Maestro engine states. It would require porting this functionality to Conductor 4 though it had been dropped given no other Conductor use cases besides Maestro relied on this. By rewriting the flow engine it would allow removal of several complex internal databases and database synchronization requirements which was attractive for simplifying operational reliability. Given Maestro did not need the full set of state engine features offered by Conductor, this motivated us to consider a flow engine rewrite as a higher priority.

The decision for Temporal was more straightforward. Temporal is optimized towards facilitating inter-process orchestration and would involve calling an external service to interact with the Temporal flow engine. Given Maestro is operating greater than a million tasks per day, many of which are long running, we felt it was an unnecessary source of risk to couple the DAG engine execution with an external service call. If our requirements went beyond lightweight state transition management we might reconsider because Temporal is a very robust control plane orchestration system, but for our needs it introduced complexity and potential reliability weak spots when there was no direct need for the advanced feature set that it offered.

After considering Option 2 and Option 3, we developed more conviction that Maestro’s architecture could be greatly simplified by not using a full DAG evaluation engine and having to maintain the state machine for two systems (Maestro and Conductor/Temporal). Therefore, we have decided to go with Option 1.

After the change

To address these issues, we completely rewrote the Maestro internal flow engine layer to satisfy Maestro’s specific needs and optimize its performance. This new flow engine is lightweight with minimal dependencies, focusing on excelling in the two primary functions mentioned above. We also replaced existing distributed job queues with internal ones to provide a strong guarantee.

The new engine is highly performant, efficient, scalable, and fault-tolerant. It is the foundation for all upper components of Maestro and provides the following guarantees to avoid race conditions:

  • A single step should only be executed by a single worker at any given time
  • Step state should never be rolled back
  • Steps should always eventually run to a terminal state
  • The internal flow state should be eventually consistent with the Maestro workflow state
  • External API and user actions should not cause race conditions on the workflow execution

Here is the new architecture diagram after the change, which is much simpler with less dependencies:

Figure 3. The architecture diagram after the evolution.

New Flow Engine Optimization

The new flow engine significantly boosts speed by maintaining state in memory. It ensures consistency by using Maestro engine’s database as the source of truth for workflow and step states. During bootstrapping, the flow engine rebuilds its in-memory state from the database, improving performance and simplifying the overall architecture. This is in contrast to the previous design in which multiple databases had to be reconciled against one another (Conductor’s tables and Maestro’s tables) or else suffer race conditions and rare orphaned job status.

The flow engine operates on in-memory flow states, resembling a write through caching pattern. Updates to workflow or step state in the database also update the in-memory flow state. If in-memory state is lost, the flow engine rebuilds it from the database, ensuring eventual consistency and resolving race conditions.

This design delivers lower latency and higher throughput, avoids inconsistencies from dual persistence, simplifies the architecture, and keeps the in‑memory view eventually consistent with the database.

Maintaining Scalability While Gaining Speed

With the new engine, we significantly boost performance by collocating flows and their tasks on the same node throughout their lifecycle. Therefore, states of a flow and its tasks will stay in a single node’s memory without persisting to the database. This stickiness and locality bring great performance benefits but inevitably impact scalability since tasks are no longer reassigned to a new worker of the whole cluster in each polling cycle.

To maintain horizontal scalability, we introduced a flow group concept to partition running flows into groups. In this way, each Maestro flow engine instance only needs to maintain ownership of groups rather than individual flows, reducing maintenance costs (e.g., heartbeat) and simplifying reconciliation by allowing each Maestro node to load flows for a group in batches. Each Maestro node claims ownership of a group of flows through a flow group actor and manages their entire lifecycle via child flow actors. If ownership is lost due to node failure or long JVM GC, another node can claim the group to resume flow executions by reconciling internal state from Maestro database. The following diagram illustrates the ownership maintenance.

Figure 4. Ownership maintenance sequence diagram.

Flow Partitioning

To efficiently distribute traffic, Maestro assigns a consistent group ID to flows/workflows by a simple stable ID assignment method, as shown in the diagram’s Partitioning Function box. We chose this simpler partitioning strategy over advanced ones, e.g. consistent hashing, primarily due to execution and reconciliation costs and consistency challenges in a distributed system.

Since Maestro decomposes workflows into hierarchical internal flows (e.g., foreach), parent flows need to interact with child flows across different groups. To enable this, the maximal group number from the parent, denoted as N’ in the diagram, is passed down to all child flows. This allows child flows, such as subworkflows or foreach iterations, to recompute their own group IDs and also ensures that a parent flow can always determine the group ID of its child flows using only their workflow identifiers.

Figure 5. Flow group partitioning mechanism diagram.

After a flow’s group ID is determined, the flow operator routes the flow request to the appropriate node. Each node owns a specific range of group IDs. For example, in the diagram, Node 1 owns groups 0, 1, and 2, while Node 3 owns groups 6, 7, and 8. The groups then contain the individual flows (e.g., Flow A, Flow B).

In this design, the group size is configurable and nodes can also have different group size configurations. The following diagram shows a flow group partitioning example while the maximal group number is changed during the engine execution without impacting any existing workflows.

Figure 6. A flow group partitioning example.

In short, Maestro flow engine shares the group info across the parent and child workflows to provide a flexible and stable partitioning mechanism to distribute work across the cluster.

Queue Optimization

We replaced both external distributed job queues in the existing system with internal ones, preserving the same fault‑tolerance and recovery guarantees while reducing latency and boosting throughput.

For the internal flow engine, the queue is a simple in‑memory Java blocking queue. It requires no persistence and can be rebuilt from Maestro state during reconciliation.

For the Maestro engine, we implemented a database‑backed in‑memory queue that provides exactly‑once publishing and at‑least‑once delivery guarantees, addressing multiple edge cases that previously required manual state correction.

This design is similar to the transactional outbox pattern. In the same transaction that updates Maestro tables, a row is inserted into the `maestro_queue` table. Upon transaction commit, the job is immediately pushed to a queue worker on the same node, eliminating polling latency. After successful processing, the worker deletes the row from the database. A periodic sweeper re-enqueues any rows whose timeout has expired, ensuring another worker picks them up if a worker stalls or a node fails.

This design handles failures cleanly. If the transaction fails, both data and message roll back atomically, no partial publishing. If a worker or node fails after commit, the timeout mechanism ensures the job is retried elsewhere. On restart, a node rebuilds its in‑memory queue from the queue table, providing at-least-once delivery guarantee.

To enhance scalability and avoid contention across event types, each event type is assigned a `queue_id`. Job messages are then partitioned by `queue_id`, optimizing performance and maintaining system efficiency under high load.

From Stateless Worker Model to Stateful Actor Model

Maestro previously used a shared-nothing stateless worker model with a polling mechanism. When a task started, its identifier was enqueued to a distributed task queue. A worker from the flow engine would pick the task identifier from the queue, load the complete states of the whole workflow (including the flow itself and every task), execute the task interface method once, write the updated task data back to the database, and put the task back in the queue with a polling delay. The worker would then forget this task and start polling the next one.

That architecture was simple and horizontally scalable (excluding database scalability considerations), but it had drawbacks. The process introduced considerable overhead due to polling intervals and state loading. The time spent in one polling cycle on distributed queues, loading complete states, and other DB queries was significant.

As Maestro engine decomposes complex workflow graphs into multiple flows, actions might involve multiple flows spanning multiple polling cycles, adding up to significant overhead (around ten seconds in the worst cases). Also, this design didn’t offer strong execution guarantees mainly because the distributed job queue could only provide at-least-once guarantees. Tasks might be dequeued and dispatched to multiple workers, workers might reset states in certain race conditions, or load stale states of other tasks and make incorrect decisions. For example, after a long garbage-collection pause or network hiccup, two workers can pick up the same task: one sets the task status as completed and then unblocks the downstream steps to move forward. However, the other worker, working off stale state, resets the task status back to running, leaving the whole workflow in a conflicting state.

In the new design, we developed a stateful actor model, keeping internal states in memory. All tasks of a workflow are collocated in the same Maestro node, providing the best performance as states are in the same JVM.

Actor-Based Model

The new flow engine fits well into an actor model. We also deliberately designed it to allow sharing certain local states (read-only) between parent, child, and sibling actors. This optimization gains performance benefits without losing thread safety due to Maestro’s use cases. We used Java 21’s virtual thread support to implement it with minimal dependencies.

The new actor-based flow engine is fully message/event-driven and can take actions immediately when events are received, eliminating polling interval delays. To maintain compatibility with the existing polling-based logic, we developed a wakeup mechanism. This model requires flow actors and their child task actors to be collocated in the same JVM for communication over the in-memory queue. Since the Maestro engine already decomposes large-scale workflow instances into many small flows, each flow has a limited number of tasks that fit well into memory.

Below is a high-level overview of the Maestro execution flow based on the actor model.

Figure 7. The high level overview of the Maestro execution.
  • When a workflow starts or during reconciliation, the flow engine inserts (if not existing) or loads the Maestro workflow and step instance from the database, transforming it into the internal flow and task state. This state remains in JVM memory until evicted (e.g., when the workflow instance reaches a terminal state).
  • A virtual thread is created for each entity (workflow instance or step attempt) as an actor to handle all updates or actions for this entity, ensuring thread safety and eliminating distributed locks and potential race conditions.
  • Each virtual thread actor contains an in-memory state, a thread-safe blocking queue, and a state machine to update states, ensuring thread safety and high efficiency.
  • Actors are organized hierarchically, with flow actors managing all their task actors. Flow actors and their task actors are kept in the same JVM for locality benefits, with the ability to relocate flow instances to other nodes if needed.
  • An event can wake up a virtual thread by pushing a message to the actor’s job queue, enabling Maestro to move toward an event-driven approach alongside the current polling-based approach.
  • A reconciliation process transforms the Maestro data model into the internal flow data.

Virtual Thread Based Implementation

We chose Java virtual threads to implement various actors (e.g. group actors and flow actors), which simplified the actor model implementation. With a smaller amount of code, we developed a fully functional and highly performant event-driven distributed flow engine. Virtual threads fit very well in use cases like state machine transitions within actors. They are lightweight enough to be created in a large number without Out-Of-Memory risks.

However, virtual threads can potentially deadlock. They’re not suitable for executing user-provided logic or complex step runtime logic that might depend on external libraries or services outside our control. To address this, we separate flow engine execution from task execution logic by adding a separate worker thread pool (not virtual threads) to run actual step runtime business logic like launching containers or making external API calls. Flow/task actors can wait indefinitely for the future of the thread poll executor to complete but don’t perform actual execution, allowing us to benefit from virtual threads while avoiding deadlock issues.

Figure 8. Virtual thread and worker thread separation.

Providing Strong Execution Guarantees

To provide strong execution guarantees, we implemented a generation ID-based solution to ensure that a single flow or task is executed by only one actor at any time, with states that never roll back and eventually reach a terminal state.

When a node claims a new group or a group with an expired heartbeat, it updates the database table row and increments the group generation ID. During node bootstrap, the group actor updates all its owned flows’ generation IDs while rebuilding internal flow states. When creating a new flow, the group actor verifies that the database generation ID matches its in-memory generation ID, otherwise rejecting the creation and reporting a retryable error to the caller. Please check the source code for the implementation details.

Figure 9. An example sequence diagram showing how generation id provides a strong guarantee.

Additionally, the new flow engine supports both event-driven execution and polling-based periodic reconciliation. Event-driven support allows us to extend polling intervals for state reconciliation at a very low cost, while polling-based reconciliation relaxes event delivery requirements to at-most-once.

Testing, Validation and Rollout

Migrating hundreds of thousands of Netflix data processing jobs to a new workflow engine required meticulous planning and execution to avoid data corruption, unexpected traffic patterns, and edge cases that could hinder performance gains. We adopted a principled approach to ensure a smooth transition:

  1. Realistic Testing: Our testing mirrored real-world use cases as closely as possible.
  2. Balanced Approach: We balanced the need for rapid delivery with comprehensive testing.
  3. Minimal User Disruption: The goal was for users to be unaware of the underlying changes.
  4. Clear Communication: For cases requiring user involvement, clear communication was provided.

Maestro Test Framework

To achieve our testing goals, we developed an adaptable testing framework for Maestro. This framework addresses the limitations of static unit and integration tests by providing a more dynamic and comprehensive approach, mimicking organic production traffic. It complements existing tests to instill confidence when rolling out major changes, such as new DAG engines.

The framework is designed to sample real user workflows, disconnecting business logic from external side effects like data reads or writes. This allows us to run workflow graphs of various shapes and sizes, reflecting the diverse use cases across Netflix. While system integrations are handled through deployment pipeline integration tests, the ability to exercise a wide variety of workflow topologies (e.g., parallel executions, for-each jobs, conditional branching and parameter passing between jobs) was crucial for ensuring the new flow engine’s correctness and performance.

The prototype workflow for the test framework focuses on auto-testing parameters, involving two main steps:

1. Caching Production Workflows:

  • Successful production instances are queried from a historical Maestro feed table over a specified period.
  • Run parameters, initiator, and instance IDs are extracted and organized into an instance data map.
  • YAML definitions and subworkflow IDs are pulled from S3 storage.
  • Both workflow definitions and instance data are cached on S3 for subsequent steps.

2. Pushing, Running, and Monitoring Workflows:

  • Cached workflow definitions and instance data are loaded.
  • Notebook-based jobs are replaced with custom notebooks, and certain job types (e.g., vanilla container runtime jobs, templated data movement jobs) and signal triggers are converted to a special no-op job type or skipped.
  • Abstract job types like Write-Audit-Publish are expressed as a single step template but are translated to multiple reified nodes of the DAG when executed. These are auto-translated into several custom notebook job types to replace the generated nodes.
  • Workflows and subworkflows are pushed, with only non-subworkflows being run using original production instance information.
  • 1. In the parent workflow, each sub-workflow is replaced with a special no-op placeholder so that the overall topology is preserved but without executing any side-effects of child workflows and avoid cases using dynamic runtime parameter logic.
  • 2. Each sub-workflow is then separately treated like a top-level parent workflow not initiated from its parent, to exercise the actual workflow steps of the sub-workflow.
  • The custom notebook internally compares all passed parameters for each job.
  • Workflow instances are monitored until termination (success or failure).
  • An email detailing failed workflow instances is generated.

Future phases of the test framework aim to expand support for native steps, more templates, Titus and Metaflow workflows, and include more robust signal testing. Further integration with the ecosystem, including dedicated Genie clusters for no-op jobs and DGS for our internal workflow UI feature verification, is also being explored.

Rollout Plan

Our rollout strategy prioritized minimal user disruption. We determined that an entire workflow, from its root instance, must reside in either the old or new flow engine, preventing mixed operations that could lead to complex failure modes and manual data reconciliation.

To facilitate this, we established a parallel infrastructure for the new workflow engine and leveraged our orchestrator gateway API to hide any routing or redirection logic from users. This approach provided excellent isolation for managing the migration. Initially, specific workflows could explicitly opt in via a system flag, allowing us to observe their execution and gain confidence. By scaling up traffic to the parallel infrastructure in direct proportion to what was scaled down from the original infrastructure, the dual infrastructure cost increase was negligible.

Once confident, we transitioned to a percentage-based cutover. In the event of a sustained failure in the new engine, our team could roll back a workflow by removing it from the new engine’s database and restarting it in the original stack. However, one consequence of rollback was that failed workflows had to restart from the beginning, recomputing previously successful steps, to ensure all artifacts were generated from a consistent flow engine.

Leveraging Maestro’s 10-day workflow timeout, we migrated users without disruption. Existing executions would either complete or time out. Upon restarting (due to failure/timeout) or triggering a new instance (due to success), the workflow would be picked up by the new engine. This effectively allowed us to gradually “drain” traffic from the old engine to the new one with no user involvement.

While the plan generally proceeded as expected with limited edge cases, we did encounter a few challenges:

  • Stuck Workflows: Around 50 workflows with defunct or incorrect ownership information entered a stuck state. In some cases, a backlog of queued instances behind a stuck instance created a race condition in which a new instance would be started immediately when an old instance was terminated, perpetually keeping the workflow on the old engine. For these, we proactively contacted users to negotiate manual stop-and-restart times, forcing them onto the new engine.
  • Configuration Discrepancies: A significant lesson learned was the importance of meticulous record-keeping and management of parallel infrastructure components. We discovered alerts, system flags, and feature flags configured for one stack but not the other. This led to a failure in a partner team’s system that dynamically rolled out a Python migration by analyzing workflow configurations. The absence of a required feature flag in the new engine stack caused the process to be silently skipped, resulting in incorrect Python version configurations for about 40 workflows. Although quickly remediated, this caused user inconvenience as affected workflows needed to be restarted and verified for no lingering data corruption issues. This issue also highlighted limitations in the testing framework since runtime configuration based on external API calls to the configuration service were not exercised in simulated workflow executions.

Despite these challenges, the migration was a success. We migrated over 60,000 active workflows generating over a million data processing tasks daily with almost no user involvement. By observing the flow engine’s lifecycle management latency, we validated a reduction in step launch overhead from around 5 seconds to 50 milliseconds. Workflow start overhead (incurred once per each workflow execution) also improved from 200 milliseconds to 50 milliseconds. Aggregating this over a million daily step executions translates to saving approximately 57 days of flow engine overhead per day, leading to a snappier user experience, more timely workflow status for data practitioners and greater overall task throughput for the same infrastructure scale.

We additionally realized significant benefits internally with reduced maintenance effort due to the new flow engine’s simplified set of database components. We were able to delete nearly 40TB of obsolete tables related to the previous stateless flow engine and saw a 90% reduction in internal database query traffic which had previously been a significant source of system alerts for the team.

Conclusion

The architectural evolution of Maestro represents a significant leap in performance, reducing overhead from seconds to milliseconds. This redesign with a stateful actor model not only enhances speed by 100X but also maintains scalability and reliability, ensuring Maestro continues to meet the diverse needs of Netflix’s data and ML workflows.

Key takeaways from this evolution include:

  • Performance matters: Even in a system designed for scale, the speed of individual operations significantly impacts user experience and productivity.
  • Simplicity wins: Reducing dependencies and simplifying architecture not only improved performance but also enhanced reliability and maintainability.
  • Strong guarantees are essential: Providing strong execution guarantees eliminates race conditions and edge cases that previously required manual intervention.
  • Locality optimizations pay off: Collocating related flows and tasks in the same JVM dramatically reduces overhead from the Maestro engine.
  • Modern language features help: Java 21’s virtual threads enabled an elegant actor-based implementation with minimal code complexity and dependencies.

We’re excited to share these improvements with the open-source community and look forward to seeing how Maestro continues to evolve. The performance gains we’ve achieved open new possibilities for low-latency workflow orchestration use cases while continuing to support the massive scale that Netflix and other organizations require.

Visit the Maestro GitHub repository to explore these improvements. If you have any questions, thoughts, or comments about Maestro, please feel free to create a GitHub issue in the Maestro repository. We are eager to hear from you. If you are passionate about solving large scale orchestration problems, please join us.

Acknowledgements

Special thanks to Big Data Orchestration team members for general contributions to Maestro and diligent review, discussion and incident response required to make this project successful: Davis Shepherd, Natallia Dzenisenka, Praneeth Yenugutala, Brittany Truong, Jonathan Indig, Deepak Ramalingam, Binbing Hou, Zhuoran Dong, Victor Dusa, and Gabriel Ikpaetuk — and and internal partners Yun Li and Romain Cledat.

Thank you to Anoop Panicker and Aravindan Ramkumar from our partner organization that leads Conductor development in Netflix. They helped us understand issues in Conductor 2.X that initially motivated the rearchitecture and helped provide context on later versions of Conductor that defined some of the core trade-offs for the decision to implement a custom DAG engine in Maestro.

We’d also like to thank our partners on the Data Security & Infrastructure and Engineering Support teams who helped identify and rapidly fix the configuration discrepancy error encountered during production rollout: Amer Hesson, Ye Ji, Sungmin Lee, Brandon Quan, Anmol Khurana, and Manav Garekar.

A special thanks also goes out to partners from the Data Experience team including Jeff Bothe, Justin Wei, and Andrew Seier. The flow engine speed improvement was actually so dramatic that it broke some integrations with our internal workflow UI that reported state transition durations. Our partners helped us catch and fix UI regressions before they shipped to avoid impact to users.

We also thank Prashanth Ramdas, Anjali Norwood, Eva Tse, Charles Zhao, Sumukh Shivaprakash, Joey Lynch, Harikrishna Menon, Marcelo Mayworm, Charles Smith and other leaders for their constructive feedback and guidance on the Maestro project.


100X Faster: How We Supercharged Netflix Maestro’s Workflow Engine was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

R2 SQL: a deep dive into our new distributed query engine

Post Syndicated from Yevgen Safronov original https://blog.cloudflare.com/r2-sql-deep-dive/

How do you run SQL queries over petabytes of data… without a server?

We have an answer for that: R2 SQL, a serverless query engine that can sift through enormous datasets and return results in seconds.

This post details the architecture and techniques that make this possible. We’ll walk through our Query Planner, which uses R2 Data Catalog to prune terabytes of data before reading a single byte, and explain how we distribute the work across Cloudflare’s global network, Workers and R2 for massively parallel execution.

From catalog to query

During Developer Week 2025, we launched R2 Data Catalog, a managed Apache Iceberg catalog built directly into your Cloudflare R2 bucket. Iceberg is an open table format that provides critical database features like transactions and schema evolution for petabyte-scale object storage. It gives you a reliable catalog of your data, but it doesn’t provide a way to query it.

Until now, reading your R2 Data Catalog required setting up a separate service like Apache Spark or Trino. Operating these engines at scale is not easy: you need to provision clusters, manage resource usage, and be responsible for their availability, none of which contributes to the primary goal of getting value from your data.

R2 SQL removes that step entirely. It’s a serverless query engine that executes retrieval SQL queries against your Iceberg tables, right where your data lives.

Designing a query engine for petabytes

Object storage is fundamentally different from a traditional database’s storage. A database is structured by design; R2 is an ocean of objects, where a single logical table can be composed of potentially millions of individual files, large and small, with more arriving every second.

Apache Iceberg provides a powerful layer of logical organization on top of this reality. It works by managing the table’s state as an immutable series of snapshots, creating a reliable, structured view of the table by manipulating lightweight metadata files instead of rewriting the data files themselves.

However, this logical structure doesn’t change the underlying physical challenge: an efficient query engine must still find the specific data it needs within that vast collection of files, and this requires overcoming two major technical hurdles:

The I/O problem: A core challenge for query efficiency is minimizing the amount of data read from storage. A brute-force approach of reading every object is simply not viable. The primary goal is to read only the data that is absolutely necessary.

The Compute problem: The amount of data that does need to be read can still be enormous. We need a way to give the right amount of compute power to a query, which might be massive, for just a few seconds, and then scale it down to zero instantly to avoid waste.

Our architecture for R2 SQL is designed to solve these two problems with a two-phase approach: a Query Planner that uses metadata to intelligently prune the search space, and a Query Execution system that distributes the work across Cloudflare’s global network to process the data in parallel.

Query Planner

The most efficient way to process data is to avoid reading it in the first place. This is the core strategy of the R2 SQL Query Planner. Instead of exhaustively scanning every file, the planner makes use of the metadata structure provided by R2 Data Catalog to prune the search space, that is, to avoid reading huge swathes of data irrelevant to a query.

This is a top-down investigation where the planner navigates the hierarchy of Iceberg metadata layers, using stats at each level to build a fast plan, specifying exactly which byte ranges the query engine needs to read.

What do we mean by “stats”?

When we say the planner uses “stats” we are referring to summary metadata that Iceberg stores about the contents of the data files. These statistics create a coarse map of the data, allowing the planner to make decisions about which files to read, and which to ignore, without opening them.

There are two primary levels of statistics the planner uses for pruning:

Partition-level stats: Stored in the Iceberg manifest list, these stats describe the range of partition values for all the data in a given Iceberg manifest file. For a partition on day(event_timestamp), this would be the earliest and latest day present in the files tracked by that manifest.

Column-level stats: Stored in the manifest files, these are more granular stats about each individual data file. Data files in R2 Data Catalog are formatted using the Apache Parquet. For every column of a Parquet file, the manifest stores key information like:

  • The minimum and maximum values. If a query asks for http_status = 500, and a file’s stats show its http_status column has a min of 200 and a max of 404, that entire file can be skipped.

  • A count of null values. This allows the planner to skip files when a query specifically looks for non-null values (e.g., WHERE error_code IS NOT NULL) and the file’s metadata reports that all values for error_code are null.

Now, let’s see how the planner uses these stats as it walks through the metadata layers.

Pruning the search space

The pruning process is a top-down investigation that happens in three main steps:

  1. Table metadata and the current snapshot

The planner begins by asking the catalog for the location of the current table metadata. This is a JSON file containing the table’s current schema, partition specs, and a log of all historical snapshots. The planner then fetches the latest snapshot to work with.

2. Manifest list and partition pruning

The current snapshot points to a single Iceberg manifest list. The planner reads this file and uses the partition-level stats for each entry to perform the first, most powerful pruning step, discarding any manifests whose partition value ranges don’t satisfy the query. For a table partitioned by day(event_timestamp), the planner can use the min/max values in the manifest list to immediately discard any manifests that don’t contain data for the days relevant to the query.

3. Manifests and file-level pruning

For the remaining manifests, the planner reads each one to get a list of the actual Parquet data files. These manifest files contain more granular, column-level stats for each individual data file they track. This allows for a second pruning step, discarding entire data files that cannot possibly contain rows matching the query’s filters.

4. File row-group pruning

Finally, for the specific data files that are still candidates, the Query Planner uses statistics stored inside Parquet file’s footers to skip over entire row groups.

The result of this multi-layer pruning is a precise list of Parquet files, and of row groups within those Parquet files. These become the query work units that are dispatched to the Query Execution system for processing.


The Planning pipeline

In R2 SQL, the multi-layer pruning we’ve described so far isn’t a monolithic process. For a table with millions of files, the metadata can be too large to process before starting any real work. Waiting for a complete plan would introduce significant latency.

Instead, R2 SQL treats planning and execution together as a concurrent pipeline. The planner’s job is to produce a stream of work units for the executor to consume as soon as they are available.

The planner’s investigation begins with two fetches to get a map of the table’s structure: one for the table’s snapshot and another for the manifest list.

Starting execution as early as possible

From that point on, the query is processed in a streaming fashion. As the Query Planner reads through the manifest files and subsequently the data files they point to and prunes them, it immediately emits any matching data files/row groups as work units to the execution queue.

This pipeline structure ensures the compute nodes can begin the expensive work of data I/O almost instantly, long before the planner has finished its full investigation.

On top of this pipeline model, the planner adds a crucial optimization: deliberate ordering. The manifest files are not streamed in an arbitrary sequence. Instead, the planner processes them in an order matching by the query’s ORDER BY clause, guided by the metadata stats. This ensures that the data most likely to contain the desired results is processed first.

These two concepts work together to address query latency from both ends of the query pipeline.

The streamed planning pipeline lets us start crunching data as soon as possible, minimizing the delay before the first byte is processed. At the other end of the pipeline, the deliberate ordering of that work lets us finish early by finding a definitive result without scanning the entire dataset.

The next section explains the mechanics behind this “finish early” strategy.

Stopping early: how to finish without reading everything

Thanks to the Query Planner streaming work units in an order matching the ORDER BY clause, the Query Execution system first processes the data that is most likely to be in the final result set.

This prioritization happens at two levels of the metadata hierarchy:

Manifest ordering: The planner first inspects the manifest list. Using the partition stats for each manifest (e.g., the latest timestamp in that group of files), it decides which entire manifest files to stream first.

Parquet file ordering: As it reads each manifest, it then uses the more granular column-level stats to decide the processing order of the individual Parquet files within that manifest.

This ensures a constantly prioritized stream of work units is sent to the execution engine. This prioritized stream is what allows us to stop the query early.

For instance, with a query like … ORDER BY timestamp DESC LIMIT 5, as the execution engine processes work units and sends back results, the planner does two things concurrently:

It maintains a bounded heap of the best 5 results seen so far, constantly comparing new results to the oldest timestamp in the heap.

It keeps a “high-water mark” on the stream itself. Thanks to the metadata, it always knows the absolute latest timestamp of any data file that has not yet been processed.

The planner is constantly comparing the state of the heap to the water mark of the remaining stream. The moment the oldest timestamp in our Top 5 heap is newer than the high-water mark of the remaining stream, the entire query can be stopped.

At that point, we can prove no remaining work unit could possibly contain a result that would make it into the top 5. The pipeline is halted, and a complete, correct result is returned to the user, often after reading only a fraction of the potentially matching data.

Currently, R2 SQL supports ordering on columns that are part of the table’s partition key only. This is a limitation we are working on lifting in the future.


Architecture


Query Execution

Query Planner streams the query work in bite-sized pieces called row groups. A single Parquet file usually contains multiple row groups, but most of the time only a few of them contain relevant data. Splitting query work into row groups allows R2 SQL to only read small parts of potentially multi-GB Parquet files.

The server that receives the user’s request and performs query planning assumes the role of query coordinator. It distributes the work across query workers and aggregates results before returning them to the user.

Cloudflare’s network is vast, and many servers can be in maintenance at the same time. The query coordinator contacts Cloudflare’s internal API to make sure only healthy, fully functioning servers are picked for query execution. Connections between coordinator and query worker go through Cloudflare Argo Smart Routing to ensure fast, reliable connectivity.

Servers that receive query execution requests from the coordinator assume the role of query workers. Query workers serve as a point of horizontal scalability in R2 SQL. With a higher number of query workers, R2 SQL can process queries faster by distributing the work among many servers. That’s especially true for queries covering large amounts of files.

Both the coordinator and query workers run on Cloudflare’s distributed network, ensuring R2 SQL has plenty of compute power and I/O throughput to handle analytical workloads.

Each query worker receives a batch of row groups from the coordinator as well as an SQL query to run on it. Additionally, the coordinator sends serialized metadata about Parquet files containing the row groups. Thanks to that, query workers know exact byte offsets where each row group is located in the Parquet file without the need to read this information from R2.

Apache DataFusion

Internally, each query worker uses Apache DataFusion to run SQL queries against row groups. DataFusion is an open-source analytical query engine written in Rust. It is built around the concept of partitions. A query is split into multiple concurrent independent streams, each working on its own partition of data.

Partitions in DataFusion are similar to partitions in Iceberg, but serve a different purpose. In Iceberg, partitions are a way to physically organize data on object storage. In DataFusion, partitions organize in-memory data for query processing. While logically they are similar – rows grouped together based on some logic – in practice, a partition in Iceberg doesn’t always correspond to a partition in DataFusion.

DataFusion partitions map perfectly to the R2 SQL query worker’s data model because each row group can be considered its own independent partition. Thanks to that, each row group is processed in parallel.

At the same time, since row groups usually contain at least 1000 rows, R2 SQL benefits from vectorized execution. Each DataFusion partition stream can execute the SQL query on multiple rows in one go, amortizing the overhead of query interpretation.

There are two ends of the spectrum when it comes to query execution: processing all rows sequentially in one big batch and processing each individual row in parallel. Sequential processing creates a so-called “tight loop”, which is usually more CPU cache friendly. In addition to that, we can significantly reduce interpretation overhead, as processing a large number of rows at a time in batches means that we go through the query plan less often. Completely parallel processing doesn’t allow us to do these things, but makes use of multiple CPU cores to finish the query faster.

DataFusion’s architecture allows us to achieve a balance on this scale, reaping benefits from both ends. For each data partition, we gain better CPU cache locality and amortized interpretation overhead. At the same time, since many partitions are processed in parallel, we distribute the workload between multiple CPUs, cutting the execution time further.


In addition to the smart query execution model, DataFusion also provides first-class Parquet support.

As a file format, Parquet has multiple optimizations designed specifically for query engines. Parquet is a column-based format, meaning that each column is physically separated from others. This separation allows better compression ratios, but it also allows the query engine to read columns selectively. If the query only ever uses five columns, we can only read them and skip reading the remaining fifty. This massively reduces the amount of data we need to read from R2 and the CPU time spent on decompression.

DataFusion does exactly that. Using R2 ranged reads, it is able to read parts of the Parquet files containing the requested columns, skipping the rest.

DataFusion’s optimizer also allows us to push down any filters to the lowest levels of the query plan. In other words, we can apply filters right as we are reading values from Parquet files. This allows us to skip materialization of results we know for sure won’t be returned to the user, cutting the query execution time further.

Returning query results

Once the query worker finishes computing results, it returns them to the coordinator through the gRPC protocol.

R2 SQL uses Apache Arrow for internal representation of query results. Arrow is an in-memory format that efficiently represents arrays of structured data. It is also used by DataFusion during query execution to represent partitions of data.

In addition to being an in-memory format, Arrow also defines the Arrow IPC serialization format. Arrow IPC isn’t designed for long-term storage of the data, but for inter-process communication, which is exactly what query workers and the coordinator do over the network. The query worker serializes all the results into the Arrow IPC format and embeds them into the gRPC response. The coordinator in turn deserializes results and can return to working on Arrow arrays.

Future plans

While R2 SQL is currently quite good at executing filter queries, we also plan to rapidly add new capabilities over the coming months. This includes, but is not limited to, adding:

  • Support for complex aggregations in a distributed and scalable fashion;

  • Tools to help provide visibility in query execution to help developers improve performance;

  • Support for many of the configuration options Apache Iceberg supports.

In addition to that, we have plans to improve our developer experience by allowing users to query their R2 Data Catalogs using R2 SQL from the Cloudflare Dashboard.

Given Cloudflare’s distributed compute, network capabilities, and ecosystem of developer tools, we have the opportunity to build something truly unique here. We are exploring different kinds of indexes to make R2 SQL queries even faster and provide more functionality such as full text search, geospatial queries, and more. 

Try it now!

It’s early days for R2 SQL, but we’re excited for users to get their hands on it. R2 SQL is available in open beta today! Head over to our getting started guide to learn how to create an end-to-end data pipeline that processes and delivers events to an R2 Data Catalog table, which can then be queried with R2 SQL.

We’re excited to see what you build! Come share your feedback with us on our Developer Discord.

Powering Partner Gateway metrics with Apache Pinot

Post Syndicated from Grab Tech original https://engineering.grab.com/pinot-partnergateway-tech-blog

Introduction

Grab operates as a dynamic ecosystem involving partners and various service providers, necessitating real-time intelligence and decision-making for seamless integration and service delivery. To facilitate this, GrabDeveloper serves as Grab’s centralized platform for developers and partners. It supports API integration, partner onboarding, and product management. It also provides tech support through staging and production portals with detailed documentation.

Working alongside Developer Home, Partner Gateway acts as Grab’s secure interface for exposing APIs to third-party entities. It enables seamless interactions between Grab’s hosted services and external consumers, such as mobile apps, web browsers, and partners. Partner Gateway enhances the experience by offering advanced metrics tracking through time-series charts and dashboards. Partner Gateway delivers actionable insights that ensure high performance, reliability, and user satisfaction in application integrations with Grab services.

Use cases

Let’s explore GrabDeveloper integration use cases with one of our partners, whom we’ll refer to as “Alpha.” Alpha is a company that specializes in producing and distributing a diverse range of perishable goods. To optimize their operations, time-series charts tracking API traffic request status codes and average API response times play a crucial role.

API traffic request service status codes chart

Time-series charts tracking API traffic request status codes offer valuable insights into the performance and reliability of APIs used for managing supply chain logistics, customer orders, and distribution networks. By monitoring these status codes, Alpha can promptly detect and resolve disruptions or failures in their digital systems, ensuring seamless operations and minimizing downtime.

Figure 1: API traffic chart from 5th Jan 2025 to 4th Mar 2025.

API average response times chart

Analyzing average response times helps the company maintain efficient communication between various systems, enhancing the speed and reliability of transactions and data exchanges. This proactive monitoring supports Alpha in delivering consistent, high-quality service to customers and partners, ultimately contributing to improved operational efficiency and customer satisfaction.

Analyzing average response times enables a company to ensure efficient communication across various systems, enhancing transaction speed and data exchange reliability. Proactive monitoring helps Alpha deliver consistent, high-quality service to customers and partners, boosting operational efficiency and customer satisfaction.

Figure 2: Average response time chart from 12 Mar 2025 3am to 12 Mar 2025 3pm (Endpoints are mocked for security purposes).

Endpoint status dashboard

For Alpha, the endpoint status dashboard delivers real-time insights into API performance, enabling swift issue resolution and seamless integration with the company’s systems. The dashboard enhances service reliability, supports business operations, and ensures uninterrupted data exchange, all of which are critical for Alpha’s business processes and customer satisfaction. Furthermore, the transparency and reliability provided by the dashboard strengthens trust in the partnership, ensuring Alpha to confidently rely on the integration to drive their digital initiatives and operational goals.

Figure 3: Endpoint status dashboard of express API for company Alpha. *Endpoints are mocked for security purposes.

Why choose Apache Pinot and what is it?

To accommodate these use cases, we need a backend storage system engineered for low-latency queries across a wide range of temporal intervals, spanning from one-hour snapshots to 30-day retrospective analyses, whereby it could contain up to ~6.8 billion rows of data in a 30 day period for a particular dataset. This led us to choose Apache Pinot for these use cases, a distributed Online Analytical Processing (OLAP) system designed for low-latency analytical queries on large-scale data with millisecond query latencies.

Apache Pinot is a real-time distributed OLAP datastore designed to deliver low-latency analytics on large-scale data. It is optimized for high-throughput ingestion and real-time query processing making it ideal for scenarios such as user-facing analytics, dashboards, and anomaly detection. Apache Pinot supports complex queries, including aggregations and filtering. It delivers sub-second response times by leveraging techniques like columnar storage, indexing, and data partitioning to achieve efficient query execution.

Data ingestion process

Figure 4: Data ingestion process.
  1. API call initiation: An API call is made on the partner application and routed through the Partner Gateway.
  2. Metric tracking: Dimensions such as client ID, partner ID, status code, endpoint, metric name, timestamp, and value (which is the metric) are tracked and uploaded to Datadog, a cloud-based monitoring platform.
  3. Kafka message transformation: Within the partner gateway code, an Apache Kafka Producer converts these metrics into Kafka messages and stores them in a Kafka Topic. Grab utilizes Protobuf for serialization and deserialization of Kafka messages. Since Grab’s Golang Kafka ecosystem does not use the Confluent Schema Registry, Kafka messages must be serialized with a magic byte which indicates that they are using Confluent’s Schema Registry, followed by the Schema ID.
  4. Serialization via Apache Flink: Serialization is managed using Apache Flink, an open-source stream processing framework. This ensures compatibility with the Confluent Schema Registry Protobuf Decoder plugin on Apache Pinot. The messages are then written to a separate Kafka Topic.
  5. Ingestion to Apache Pinot: Messages from the Kafka Topic containing the magic byte are ingested directly into Pinot, which references the Confluent Schema Registry to accurately deserialize the messages.
  6. Query execution: Queries on the Pinot table can be executed via the Pinot Rest Proxy API.
  7. Data visualization: Users can view their project charts and dashboards on the GrabDeveloper Home UI, where data points are retrieved from queries executed in step 6.

Challenges faced

During the initial setup, we encountered significant performance challenges when executing aggregation queries on large datasets exceeding 150GB. Specifically, attempts to retrieve and process data for periods ranging from 20 to 30 days resulted in frequent timeout issues as the queries took longer than 10 seconds. This was particularly concerning as it compromised our ability to meet our Service Level Agreement (SLA) of delivering query results within 300 milliseconds. The existing query infrastructure struggled to efficiently manage the volume and complexity of data within the required timeframe, necessitating optimization efforts to improve performance and reliability.

Solution

Drawing from the insights gained on the limitations of our initial solutions, we implemented these strategic optimizations to significantly enhance our table’s performance.

Partitioning by metric name

  • Improved data locality: Partitioning the Kafka Topic by metric name ensures that related data is grouped together. When a query filters on a specific metric, Pinot can directly access the relevant partitions, minimizing the need to scan unrelated data. This significantly reduces I/O overhead and processing time.
  • Efficient query pruning: By physically partitioning data, only the servers holding the relevant partitions are queried. This leads to more efficient query pruning, as irrelevant data is excluded early in the process, further optimizing performance.
  • Enhanced parallel processing: Partitioning enables Pinot to distribute queries across multiple nodes, allowing different metrics to be processed in parallel. This leverages distributed computing resources, accelerating query execution and improving scalability for large datasets.

Column based on aggregation intervals

Table 1
  • Facilitates time-based aggregations: Rounded time columns (e.g., Timestamp_1h for hourly intervals) group data into coarser time buckets, enabling efficient aggregations such as hourly or daily metrics. This simplifies indexing and optimizes storage by precomputing aggregates for specific time intervals.
  • Efficient data filtering: Rounded time columns allow for precise filtering of data within specific aggregation intervals. For example, the query SELECT SUM(Value) FROM Table WHERE Timestamp_1h = '2025-01-20 01:00:00' can exclude irrelevant columns (e.g., column 2) and focus only on rows within the specified time interval, further enhancing query efficiency.

Utilizing the Star-tree index in Apache Pinot

The Star-tree Index in Apache Pinot is an advanced indexing structure that enhances query performance by pre-aggregating data across multiple dimensions (e.g., D1, D2). It features a hierarchical tree with a root node, leaf nodes (holding up to T records), and non-leaf nodes that split into child nodes when exceeding T records. Special star nodes store pre-aggregated records by omitting the splitting dimension. The tree is constructed based on a dimensionSplitOrder, dictating node splitting at each level.

Sample table configuration for Star-tree index:

"tableIndexConfig": {
  "starTreeIndexConfigs": [{
    "dimensionsSplitOrder": [
      "Metric",
      "Endpoint",
      "Timestamp_1h"
    ],
    "skipStarNodeCreationForDimensions": [
    ],
    "functionColumnPairs": [
      "AVG__Value"
    ],
    "maxLeafRecords": 1
  }],
  ...
}

Configuration explanation:

  • dimensionsSplitOrder: This specifies the order in which dimensions are split at each level of the tree. The order is “Metric”, “Endpoint”, “Timestamp_1h”. This means the tree will first split by Metric, then by Endpoint, and finally by Timestamp_1h.
  • skipStarNodeCreationForDimensions: This array is empty, indicating that star nodes will be created for all dimensions specified in the split order. No dimensions are omitted from star node creation.
  • functionColumnPairs: This specifies the aggregation functions to be applied to columns when creating star nodes. The configuration includes “AVG__Value”, meaning the average of the “Value” column will be calculated and stored in star nodes.
  • maxLeafRecords: This is set to 1, indicating that each leaf node will contain only one record. If a node exceeds this number, it will split into child nodes.

Star-tree diagram

Figure 5: Star-tree Index Structure.

Components:

  • Root node (orange): This is the starting point for traversing the tree structure.
  • Leaf node (blue): These nodes contain up to a configurable number of records, denoted by T. In this configuration, maxLeafRecords is set to 1, meaning each leaf node will contain a maximum of one record.
  • Non-leaf node (green): These nodes will split into child nodes if they exceed the maxLeafRecords threshold. Since maxLeafRecords is set to 1, any node with more than one record will split.
  • Star-node (yellow): These nodes store pre-aggregated records by omitting the dimension used for splitting at that level. This helps in reducing the data size and improving query performance.

Example:

A practical explanation of the start-tree diagram would be to display the star-tree documents in a table format along with the sample queries used to retrieve the data.

Table 2: Star-tree documents table

Sample queries:

Select SUM(Value) FROM Table:
With no group-by clause, select the Star-Node for all dimensions (document 19) to quickly obtain the aggregated result of 250 by processing just this document.

Select SUM(Value) FROM Table WHERE Metric = 'XYZ_Req_Count':
Select the node with XYZ_Req_Count for Metric, and the Star-Node for Endpoint and Timestamp_1h (document 12). This reduces processing to one document, returning an aggregated result of 130, instead of filtering and aggregating three documents (documents 7,8 9)

SELECT SUM(Value) FROM Table WHERE Timestamp_1h = '2025-01-20 00:00:00':
Select the Star-Node for Metric and Endpoint, and the node with '2025-01-20 00:00:00' for Timestamp_1h (document 16). This allows aggregation from a single document, yielding a result of 40.

SELECT SUM(Value) FROM Table GROUP BY Endpoint:
With a group-by on Endpoint, select the Star-Node for Metric and Timestamp_1h, and all non Star-Node for Endpoint (documents 13, 14, 15). Process one document per group to obtain the group-by results efficiently.

Comparing performance after the optimization

Figure 6: Chart of query latency with and without optimization.

The graph above in Figure 6, provides a comparison analysis of query performance, showcasing the significant improvements achieved through the implemented optimization solutions. The query execution times are significantly reduced, as evidenced by the logarithmic scale values.

For the first query which calculates the latency for a particular aggregation interval, the log scale indicates a reduction from 4.64 to 2.32, translating to a decrease in query latency from 43,713 to 209 milliseconds.

Similarly, the second query, which aggregates the sum of the latency based on the tags for a particular metric, shows a log scale reduction from 3.71 to 1.54, with query latency improving from 5,072 to 35 milliseconds. These results underscore the efficacy of optimization in enhancing query performance, enabling faster data retrieval and processing

Tradeoffs

Star-tree indexes in Apache Pinot are designed to significantly enhance query performance by pre-computing aggregations. This approach allows for rapid query execution by utilizing pre-calculated results, rather than computing aggregations on-the-fly. However, this performance boost comes with a tradeoff in terms of storage space.

Before implementing the Star-tree index, the total storage size for 30 days of data was approximately 192GB. With the Star-tree index, this increased to 373GB, nearly doubling the storage requirements. Despite the increase in storage, the performance benefits substantially outweigh the costs associated with additional storage.

The cost impact is relatively minor. We utilize AWS gp3 EBS volumes, which roughly cost $14.48 USD monthly for the extra table (calculated as 0.08 USD x 181 GB). This cost is considered insignificant when compared to the substantial gains in query performance. Alternatively, precomputing the metrics via an ETL job is also feasible; however, it is less cost-effective due to the additional expenses required to maintain the pipeline.

The decision to use Star-tree indexes is justified by the dramatic improvement in query speed, which enhances user experience and efficiency. The modest increase in storage costs is a worthwhile investment for achieving optimal performance.

Conclusion

In conclusion, Grab’s integration of Apache Pinot as a backend solution within the Partner Gateway represents a forward-thinking strategy to meet the evolving demands of real-time analytics. Apache Pinot’s ability to deliver low-latency queries empowers our partners with immediate, actionable insights into API performance that enhances their integration experience and operational efficiency. This is crucial for partners who require rapid data access to make informed decisions and optimize their services.

The adoption of Star-tree indexing within Pinot further refines our analytics infrastructure by strategically balancing the trade-offs between query latency and storage costs. This optimization ensures Partner Gateway can support a diverse range of use cases with subsecond query latencies while maintaining high performance and reliability in service delivery reinforcing Grab’s commitment to delivering superior performance across its ecosystem.

Ultimately, the integration of Apache Pinot enhances Grab’s real-time analytics capabilities while empowering the company to drive innovation and consistently deliver exceptional service to both partners and users.

Credits to Manh Nguyen from the Coban Infrastructure Team, Michael Wengle from the Midas Team and Yuqi Wang from the DevHome team.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
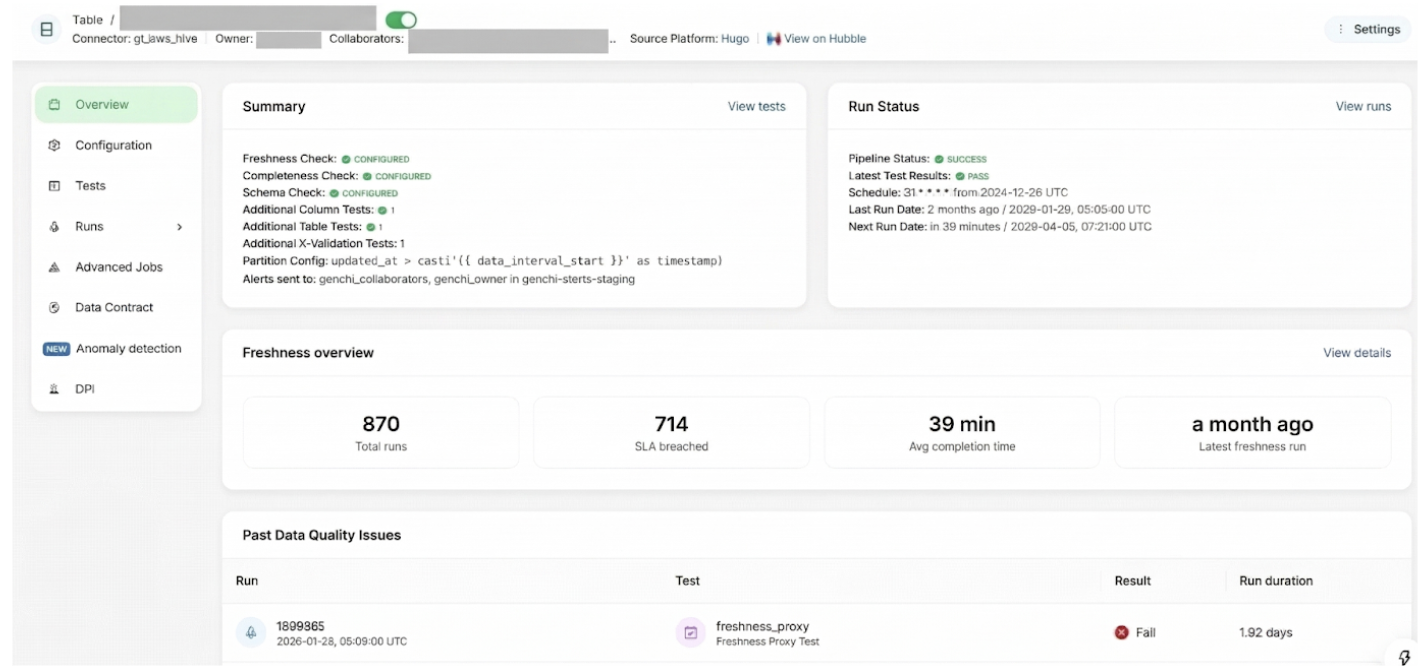
From Facts & Metrics to Media Machine Learning: Evolving the Data Engineering Function at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/from-facts-metrics-to-media-machine-learning-evolving-the-data-engineering-function-at-netflix-6dcc91058d8d

By Dao Mi, Pablo Delgado, Ryan Berti, Amanuel Kahsay, Obi-Ike Nwoke, Christopher Thrailkill, and Patricio Garza

At Netflix, data engineering has always been a critical function to enable the business’s ability to understand content, power recommendations, and drive business decisions. Traditionally, the function centered on building robust tables and pipelines to capture facts, derive metrics, and provide well modeled data products to their partners in analytics & data science functions. But as Netflix’s studio and content production scaled, so too have the challenges — and opportunities — of working with complex media data.

Today, we’re excited to share how our team is formalizing a new specialization of data engineering at Netflix: Media ML Data Engineering. This evolution is embodied in our latest collaboration with our platform teams, the Media Data Lake, which is designed to harness the full potential of media assets (video, audio, subtitles, scripts, and more) and enable the latest advances in machine learning, including latest transformer model architecture. As part of this initiative, we’re intentionally applying data engineering best practices — ensuring that our approach is both innovative and grounded in proven methodologies.

The Evolution: From Traditional Tables to Media Tables

Traditional data engineering at Netflix focused on building structured tables for metrics, dashboards, and data science models. These tables were primarily structured text or numerical fields, ideal for business intelligence, analytics and statistical modeling.

However, the nature of media data is fundamentally different:

  • It’s multi-modal (video, audio, text, images).
  • It contains derived fields from media (embeddings, captions, transcriptions…etc)
  • It’s unstructured and massive in scale when parsed out.
  • It’s deeply intertwined with creative workflows and business asset lineage.

As our studio operations (see below) expanded, we saw the need for a new approach — one that could provide centralized, standardized, and scalable access to all types of media assets and their metadata for both analytical and machine learning workflows.

The Rise of Media ML Data Engineering

Enter Media ML Data Engineering — a new specialization at Netflix that bridges the gap between traditional data engineering and the unique demands of media-centric machine learning. This role sits at the intersection of data engineering, ML infrastructure, and media production. Our mission is to provide seamless access to media assets and derived data (including outputs from machine learning models) for researchers, data scientists, and other downstream data consumers.

Key Responsibilities

  • Centralized Media Data Access: Building, cataloging and maintaining the data and pipelines that populates the Media Data Lake, a data platform for storing and serving media assets and their metadata.
  • Asset Standardization: Standardizing media assets across modalities (video, images, audio, text) to ensure consistency and quality for ML applications in partnership with domain engineering teams.
  • Metadata Management: Unifying and enriching asset metadata, making it easier to track asset lineage, quality, and coverage.
  • ML-Ready Data: Exposing large corpora of assets for early-stage algorithm exploration, benchmarking, and productionization.
  • Collaboration: Partnering closely with domain experts, algorithm researchers, upstream content engineering teams and (machine learning & data) platform colleagues to ensure our data meets real-world needs.

This new role is essential for bridging the gap between creative media workflows and the technical demands of cutting-edge ML.

Introducing the Media Data Lake

To enable the next generation of media analytics and machine learning, we are building the Media Data Lake at Netflix — a data lake designed specifically for media assets at Netflix using LanceDB. We have partnered with our data platform team on integrating LanceDB into our Big Data Platform.

Architecture and Key Components

  • Media Table: The core of the Media Data Lake, this structured dataset captures essential metadata and references to all media assets. It’s designed to be extensible, supporting both traditional metadata and outputs from ML models (including transformer-based embeddings, media understanding research and more).
  • Data Model: We are developing a robust data model to standardize how media assets and their attributes are represented, making it easier to query and join across schemas.
  • Data API: An pythonic interface that will provide programmatic access to the Media Table, supporting both interactive exploration and automated workflows.
  • UI Components: Off-the-shelf UI interfaces enable teams to visually explore assets in the media data lake, accelerating discovery and iteration for ICs.
  • Online and Offline System Architecture: Real-time access for lightweight queries and exploration of raw media assets; scalable large batch processing for ML training, benchmarking, and research.
  • Compute: distributed batch inference layer capable of processing using GPUs and media data processing at scale using CPUs.

Starting Small with New Technology

Our initial focus this past year has been on delivering a “data pond” — a mini-version of the Media Data Lake targeted at video/audio datasets for early stage model training, evaluation and research. All data for this phase comes from AMP, our internal asset management system and annotation store, and the scope is intentionally small to ensure a solid, extensible foundation could be built while introducing a new technology into the company. We are able to perform data exploration of the raw media assets to build up an intuitive understanding of the media via lightweight queries to AMP.

Media Tables: The New Foundation for ML and Innovation

One of the most exciting developments is the rise of media tables — structured datasets that not only capture traditional metadata, but also include the outputs of advanced ML models.

These media tables power a range of innovative applications, such as:

  • Translation & Audio Quality Measures: Managing audio clips and features via text-to-speech models for engineering localization quality metrics.
  • Media Fidelity Restoration: Research on restoration of videos to HDR for remastering and other image technology use-cases.
  • Story Understanding and Content Embedding: Structuring narrative elements extracted from textual evidence and video of a title to increase operational efficiency in title launch preparation and ratings, e.g. detection of smoking, gore, NSFW scenes in our titles.
  • Media Search: Leverage multi-modal vector search to find similar keyframes, shots, dialogue to facilitate research and experimentation.

These tables built on top of LanceDB are designed to scale, support complex queries, and serve both research and other data science & analytical needs.

The Human Side: New Roles and Collaboration

Media ML Data Engineering is a team sport. Our data engineers partner with domain experts, data scientists, ML researchers, upstream business ops and content engineering teams to ensure our data solutions are fit for purpose. We also work closely with our friendly platform teams to ensure technological breakthroughs that are beneficial beyond our small corner of the universe could become horizontal abstractions that benefit the rest of Netflix. This collaborative model enables rapid iteration, high data quality, innovative use cases and technology re-use.

Looking Ahead

The evolution from traditional data engineering to Media ML data engineering — anchored by our media data lake — is unlocking new frontiers for Netflix:

  • Richer, more accurate ML models trained on high-quality, standardized media data.
  • Supercharge ML Model evaluations via quick iteration cycles on the data.
  • Faster experimentation and productization of new AI-powered features.
  • Deeper insights into our content and creative workflows via metrics constructed from Media ML algorithms inferred features.

As we continue to grow the media data lake, be on the lookout for subsequent blog posts sharing our learnings and tools with the broader media ml & data engineering community.


From Facts & Metrics to Media Machine Learning: Evolving the Data Engineering Function at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.