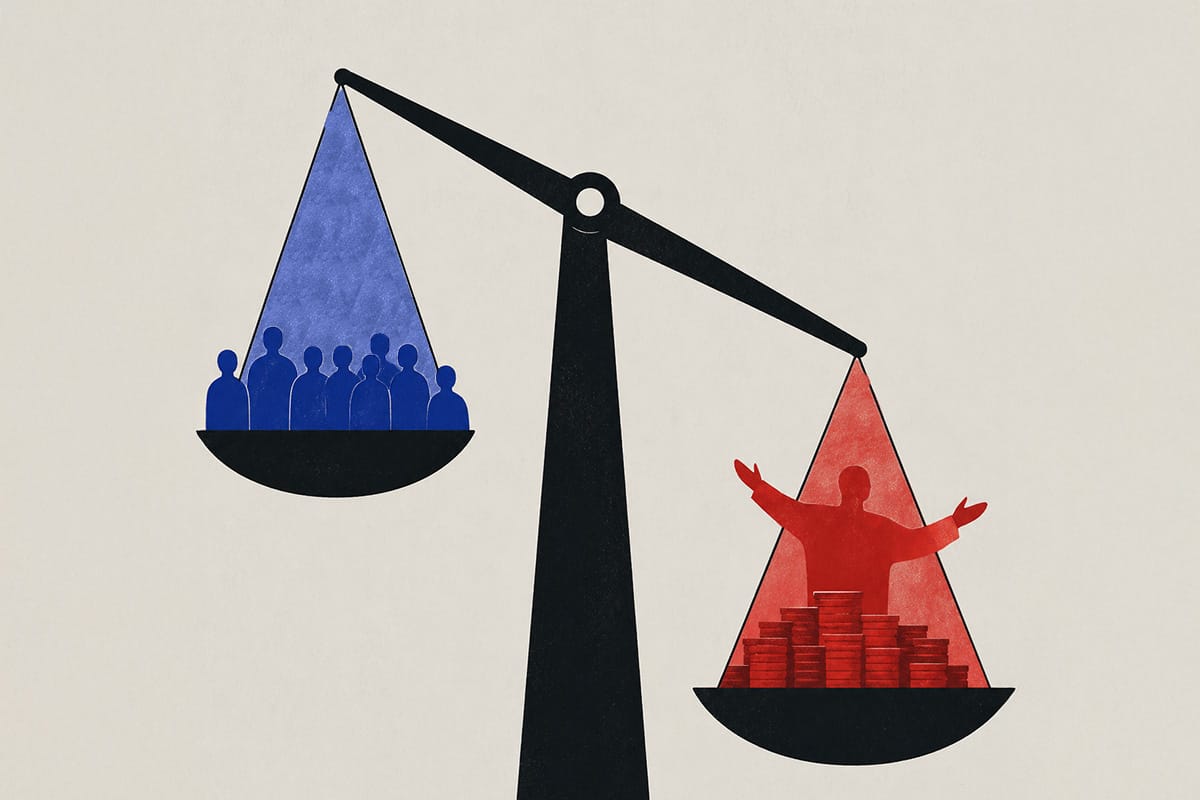
Да си го признаем – твърдата ръка е на почит в България. Дори сред избирателите на малкото партии, смятани за демократични. Да погледнем отношението към членовете на служебния кабинет на Андрей Гюров, асоцииран (кабинетът, впрочем и Гюров) с ПП–ДБ – единствената проевропейска и що-годе демократична парламентарно представена коалиция. „Звездата“ в правителството обаче се оказа не Андрей Янкулов, олицетворяващ стремежа на ПП–ДБ към правосъдна реформа. Лаврите обра вътрешният министър Емил Дечев в комплект с и.д. главен секретар на МВР Георги Кандев. За последен път споменаването на длъжността главен секретар на МВР пораждаше такова благопочитание преди повече от 20 години, когато постът се заемаше от Бойко Борисов. А вицове за Чък Норис бяха рециклирани с имената на министъра и професионалния ръководител на МВР, например: „Като малък Емил Дечев винаги карал баба си да си изяжда закуската.“
Овациите за Дечев и Кандев впрочем бяха заслужени.
Но не защото те олицетворяваха твърдата ръка, подвизавайки се като шерифи в каубойски филм, както ги представяше народната любов, а именно защото не го правеха. Вместо да организират показни акции с мижав ефект, те разшириха обхвата на проверките за купен и контролиран вот. В навечерието на изборите Дечев отчете повече от 2000 сигнала за изборни нарушения (за сравнение, преди изборите през 2024 г. те са били 612), 534 бързи и досъдебни производства – (през 2024 г. са били 70, а разликата между бързото и досъдебното производство е, че първото е под ръководството на МВР, а второто – на прокуратурата). Без да пропускаме над 1 200 000 конфискувани евро, предназначени вероятно за купуване на гласове. А веднага след края на изборния ден МВР оповести и за кои политически субекти са отправени сигналите. Очаквано – най-много са били за ДПС (631), следвано от ГЕРБ (318). За останалите партии и коалиции са постъпили по по-малко от 20 сигнала.
Как беше преди?
Постигнатото от Дечев и Кандев заедно с министри от правителството на Гюров – като социалния Хасан Адемов и земеделския Иван Христанов – е значимо не само в количествено отношение. А защото не се свежда до обичайния расизъм и етническата дискриминация, в които обикновено се изразява борбата с купения и контролирания вот. Досега тази „борба“ приемаше основно две форми – показни акции в ромски квартали и опити за ограничаване на гласуването на българските изселници в Турция. Известно изключение от ограничаването до тези практики имаше по времето, когато вътрешен министър беше Бойко Рашков, който разпореждаше и проверки във фирми в опит да се ограничи корпоративният вот.
Обичайните акции срещу купения вот в ромски квартали включваха показни арести на лихвари с изземване на събирани от тях лични карти и списъци с имена, както и на магазинери, продаващи на вересия. Задържаха се и хора с криминално минало, у които са намерени я оръжия, я наркотици, я пари, я други забранени или незаконни неща (например стоки без бандерол). Така, от една страна, проблемът с купения и контролирания вот се свеждаше до ромите, от друга – се приравняваше до различни форми на престъпност, нямащи нищо общо с политическите права на гражданите.
Понякога обект на акциите ставаха не само заподозрените, а по-скоро всички, които живеят в определен квартал или просто го посещават. През 2021 г. например, по времето на Рашков, имаше случаи полицията да сформира КПП-та на входа на махали и да проверява всички преминаващи автомобили.
Тази практика обаче бледнее пред размаха на репресивността на бившия кмет на Кюстендил Петър Паунов. През 2011 г. той въведе КПП-та и пропускателен режим в изборния ден на местата, където гласуват роми, с цел „да няма напрежение и провокации и да не се затруднява работата на комисиите“. През 2015 г. пък Паунов организира референдум, на който гражданите на Кюстендил да гласуват дали той да се кандидатира за кмет, като не допусна до него жителите на ромския квартал. Комисията за защита от дискриминация се самосезира по случая.
Опити за възпрепятстване на изселниците в Турция
Интензивността на усилията да се попречи на българските изселници в Турция да гласуват зависи от отношението на властта към партията, за която преобладаващата част от тях възнамеряват да дадат гласа си. А понякога – и от желанието да се попречи на успешното представяне на изборите на нов политически субект, за какъвто биха гласували мнозинството от българите в чужбина. При втората хипотеза изселниците в Турция са „косвена жертва“.
Тази втора хипотеза беше приложена на практика на последните избори през април 2026 г., когато броят на избирателните секции в страните извън ЕС беше ограничен до максимум 20. Основното опасение на парламентарното мнозинство, приело промяната в Изборния кодекс (ИК), беше политическият проект на Румен Радев. Но и Делян Пеевски нямаше интерес изселниците да гласуват, защото в Турция не се радва на особена популярност.
Промяната в ИК е римейк на подобна от 2016 г., инициирана от Патриотичния фронт, чиято основна цел беше да се попречи на българските граждани да гласуват, а косвените жертви се оказаха имигрантите в други страни извън ЕС. Впрочем и тогава мярката беше отчасти в полза на ДПС. Същата година бившият председател на ДПС Лютви Местан създаде своя партия – ДОСТ, с която, в коалиция с НДПС на Орхан Исмаилов, се включи в изборната надпревара през 2017 г., разчитайки най-вече на избирателите от Турция. И макар да получи малко над 17% от гласовете извън България и 21,59% в Кърджали, общият резултат от близо 3% не беше достатъчен за влизане в парламента.
Друга практика за възпрепятстване на изселниците е опитът физически да им се попречи да гласуват в България. През същата 2017 година Валери Симеонов (председател на НФСБ, част от Патриотичния фронт) упражни физическо насилие върху жени, дошли от Турция за изборите. Той нарече една от тях „нагла“, защото „си знаеше правата“, и я определи като „пълничката баба“.
Трябва да се признае, че въпреки расизма и ксенофобията си, акциите в махалите и затрудняването на изселниците в Турция да упражняват правото си на глас са опити за справяне със системни проблеми в българския политически живот. И те са, че местата с компактно ромско население са особено уязвими на контролиран вот, а българските турци – поне до изборите на 19 април 2026 г., когато досегашният модел претърпя сериозни поражения – масово гласуват за ДПС (понякога се появява конкуренция в лицето на друга „турска“ партия, която бързо залязва).
За да е такъв обаче т.нар. етнически вот, има причини и те не се премахват с козметично замазване на симптомите. Основният проблем е
паразитирането върху уязвимостта с политически цели.
Уязвимостта може да има много лица: бедност и задлъжнялост, страх да не разрушат единственото ти жилище, дискриминация и омраза от страна на мнозинството. Но също и увреждане, зависимост от работодател и липса на алтернативи за работа, необходимост от инфраструктура и пр.
Нещата всъщност не опират до етноса, нито до характеристиките на населеното място, макар ромите, турците и хората в малките населени места да са по-уязвими. Но дори софиянци бяха „наказани“, че са избрали за кмет Васил Терзиев, който пък не се е снимал с Пеевски. Докато столичани се ядосват защо е зациклил ремонтът на бул. „Стамболийски“ и защо не се извършват редица подобрения в града, се оказва, че София е получила едва 13% от бюджетното финансиране, което е заявила – по-малко в парично изражение, отколкото например Ветово или Гърмен.
В крайна сметка контролираният вот опира до политически натиск,
който, ако не срещне никаква съпротива, както беше по времето на правителството на Росен Желязков, се разпространява като гангрена далеч отвъд „обичайните заподозрени“ гласоподаватели в ромските квартали и „крепостите“ на ДПС. Ала както беше казал експертът по сигурност и бивш заместник вътрешен министър Филип Гунев, най-лесно е МВР да се концентрира върху криминалния контингент, защото „нагоре вече е опасно“ и „политически рисково“.
Как беше сега?
В опитите за ограничаване на контролирания вот служебното правителство на Андрей Гюров, наред с обичайните акции в рискови ромски квартали, се опита да стигне и там, където „вече е опасно“. То реагираше на сигнали срещу кметове, общински съветници, кандидат-депутати с имунитет.
Мащабът на проверките показа, че опити за влияние върху вота може да се правят на най-различни места. Беше арестуван например директорът на пощата в Кърджали по сигнал, че е отправял заплахи, свързани с изборите. Според МВР той е карал служители на хуманитарна организация (по-късно се разбра, че става дума за Българския червен кръст) да казват, че храната, която дават на уязвими хора, е подарък от ДПС.
Друга форма на натиск са заплахите към хора с увреждания и близките им, които се грижат за тях, че ако не гласуват за определена партия, няма да получат пари за личен асистент или размерът на средствата ще бъде намален. Това е един от разнообразните методи за шантаж, свързан с достъпа до социални програми.
Вотът може да се контролира също чрез работодатели, които нареждат на служителите си за кого да гласуват – под страх от уволнение или намаляване на парите „под масата“, или пък с обещание за „материално стимулиране“. Колкото по-крупни са тези работодатели, толкова по-голям е ефектът. ТЕЦ „Бобов дол“ например е бил тема на журналистически разследвания във връзка с контролирания вот. Няколко дни преди изборите полицаи от управлението на МВР в Кюстендил извършиха проверки и иззеха документи, списъци и пари, които дават сериозни основания да се предположи, че „има нещо гнило“.
Разширяването на периметъра на борбата с изборните нарушения ясно показа,
че проблемът с купения и контролирания вот не е въпрос на етнос, култура или майчин език, а идва отгоре. Както гласи известната до баналност поговорка, рибата се вмирисва откъм главата. Докато правосъдната система обаче е политически зависима, не може да се очаква, че „главата“ ще отговаря за престъпленията си.
Освен това – защото като съдия е наясно докъде се простират границите на действие на един вътрешен министър – Дечев не си позволи зрелищни акции, които впоследствие да се обърнат срещу него – например да изгони Борислав Сарафов от кабинета на главния прокурор, за което беше нееднократно призоваван. За разлика от Бойко Рашков, който през 2022 г. разпореди да бъдат арестувани за 24 часа Бойко Борисов, пиарката му Севдалина Арнаудова и бившият министър на икономиката Владислав Горанов. Макар тази акция да предизвика бурна радост сред критиците на ГЕРБ, тя се оказа фиаско, за което ПП, а покрай тях и ДБ платиха висока цена.
Макар да не стигна до вмирисаната глава, постижението на правителството на Андрей Гюров е, че не се задоволи само с опашката на рибата, а се придвижи малко към перките ѝ, между острите и отровни шипове. Кой знае, ако някое правителство успее да стигне до главата, току-виж се окаже, че тя получава нареждания от друга, по-голяма и по-миризлива глава.
Researchers have reverse-engineered a piece of malware named Fast16. It’s almost certainly state-sponsored, probably US in origin, and was deployed against Iran years before Stuxnet:
“…the Fast16 malware was designed to carry out the most subtle form of sabotage ever seen in an in-the-wild malware tool: By automatically spreading across networks and then silently manipulating computation processes in certain software applications that perform high-precision mathematical calculations and simulate physical phenomena, Fast16 can alter the results of those programs to cause failures that range from faulty research results to catastrophic damage to real-world equipment.”
Живея в една абсурдна политическа среда. Всеки път, когато се случи нещо невъобразимо, си казвам, че това е дъното, но след това се оказва, че има и друго дъно, още по-дълбоко. И така вървим към ядрото на земята. Иска ми се да се събудя от кошмара или да напусна кошмарната кинопрожекция, но и двете не ми се получават. Всички около мен са се вторачили в наближаващите междинни избори тук (САЩ) с надежда, страх и тревожност.
Две партии – две философии за властта
С наближаването на тези избори през ноември 2026 г. Демократическата и Републиканската партия оформят рязко различаващи се стратегии. Разликите са не само идейни, а и философски: как се печели власт, на кого се говори като избирател и кой плаща сметките. Партийните послания са продукт не само на идеология, а и на финансиране, вътрешнопартийни противоречия и структурни предимства. С други думи, не е важно единствено какво казваш, а с кого си свързан, докато го казваш.
Демократите влизат в цикъла на 2026 г. със самочувствието на партията на „гражданската енергия“, малките дарители и активизма „по места“. Доста ранните финансови успехи, почиващи на хиляди малки дарения, и ентусиазмът на прогресивните PAC-ове¹ им позволява да създадат удобен наратив: „Ние сме подкрепяни от хората, не от милиардерите.“ Кандидати като Джеймс Таларико, Джон Ософ и Шерод Браун вече са събрали милиони долари, което говори за мащаба на прогресивния ентусиазъм. Но зад тази вълна от малки дарения се крие старият проблем – вътрешното разделение.
Прогресивното крило настоява за системни реформи, икономическа справедливост и борба с неравенствата. Умерените, особено в колебаещите се райони, предпочитат по-тих тон, стабилност, прагматизъм и „да не плашим центъра“. Общият знаменател? Защита на демокрацията и противопоставяне на политики, асоциирани с Доналд Тръмп. Но тук изпъква един премълчаван проблем: демократите упорито подценяват реалната опасност от нечестни избори. А тя, при управление с открито пренебрежение към институциите, не е хипотеза, а реална възможност.
Още по-проблематично е неразбирането или пренебрегването на културното разделение на обществото. Избирателите все по-рядко гласуват според икономическите си интереси и все по-често – според културната си идентичност. Няма го класовото съзнание на Карл Маркс. Докато демократите обясняват как икономическите им програми „помагат на всички“, републиканците говорят за разпадащия се традиционен свят – такъв, какъвто го знаем и харесваме. И страхът, за разлика от икономическите данни, определя политическия избор.
Републиканците – ред, страх и чекове с много нули
Републиканската партия залага на по-различен подход: организационна мощ, структурни предимства и големи донори. През 2025 г. републиканските национални комитети събраха повече средства от демократите, а ролята на супер PAC-ове като Senate Leadership Fund и Congressional Leadership Fund расте. Като добавим към това щедрите дарения на Илон Мъск, и наративът се оформя: партията на бизнеса ще успокои икономическото недоволство, ще подобри пограничната сигурност и ще се справи с културната тревожност. Този подход енергизира твърдото електорално ядро на MAGA.
Както винаги, социалните мрежи са централната арена на конфликтите. Руското присъствие не повтаря шока от 2016 г., но остава устойчив фон за внасяне на неистини и съмнения. Целта е по-скоро да накараш избирателя да не вярва на нищо. Изкуствен интелект, фалшиви новинарски сайтове, координирани публикации в X, Telegram и периферни платформи работят за задълбочаване на недоверието. Демократите залагат на TikTok и Instagram, на инфлуенсъри и кратки видеа, които „разказват политиката“. Републиканците доминират в екосистеми, построени около личности и завъртени през гнева и усещането за несправедливост. Две различни дигитални пространства почти без припокриване и без шанс да се убеди избирател, чиито медийни алгоритми му представят само това, което очаква да види.
Бунтът като политически жест
Към тези сравнително добре структурирани стратегии трябва да добавим и неструктурираното, а именно емоцията. Най-ефективната ѝ форма днес е популизмът, подправен с обещания за радикална промяна. Преди около две години във Великобритания Киър Стармър спечели с обещание за стабилност и бързо стана непопулярен. В Япония Санае Такаичи победи с конфронтация и радикални предложения и продължава да бъде харесвана в иначе традиционно мъжка политическа среда. Същото видяхме и в Ню Йорк с Мамдани, който се представи като бунтар в кампанията си, и засега подкрепата му продължава да е висока. Изглежда, че в сегашните времена избирателите предпочитат бунта пред реконструкцията. Гласува се със сърцето, а не с разума. Разочарованието идва после.
Трудно ми е да избегна паралелите с българските избори от 19 април. И в България имаше съмнения, изказани от евродепутатка, за руска намеса, а TikTok закри десетки фалшиви акаунти. Социалното и културно разделение е сходно, а търсенето на „рязка промяна“ – същото.
Докато американските партии се мъчат да обединят разцепени крила, българските трудно формулират ясно разпознаваеми послания. Избирателят по традиция се впечатлява от личности, не от програми. От Сакскобургготски, през Станишев, Борисов, до Радев наказателният вот и отричането на статуквото тежат повече от всяка управленска платформа. Освен антикорупционните и антиолигархични послания, подкрепени с близо десет години популизъм по време на президентските мандати на Радев, политическата му програма е неясна. Не може да се разбере и от парламентарните членове на „Прогресивна България“, които засега са група от няколко известни спортисти, някои познати лица от служебните кабинети на Радев и други с неизяснени позиции.
Остава популизмът само с няколко от множеството примери: най-високия пилон с българското знаме в Европа, недопустимия от конституционна гледна точка референдум за еврото, последното новогодишно поздравление като президент, в което той пак критикува приемането на еврото, а в същото време подчертава, че България принадлежи към ЕС заради „цивилизационния си принос“. Всички тези примери, включително имена на успешни атлети в партийните листи, са пряко свързани с големия разказ на българската национална идентичност – гордост, бунт и символи на величие. Политиката се превръща в емоционален спектакъл, а не се държи като програма за бъдещето.
Разумът губи и емоцията печели
Докато републиканците в САЩ определено разчитат на страха и на емоциите, които той предизвиква у избирателите, демократите все още колебливо се опитват да активират други чувства у своите избиратели за междинния вот през 2026 г. А резултатите от българските и други избори показват едно и също: когато недоволството е повсеместно, избирателят търси не най-добрата политика, а най-силното чувство. Питате се дали в Унгария все пак не надделя разумът? Може би разумът надделя, защото страхът от заплахите на Орбан престана да действа.
1PAC (Political Action Committee) е организация, която набира и разходва средства за подкрепа или противопоставяне на кандидати и политики в изборния процес в САЩ.
Catering to the small form factor PC market, Gigabyte has released a low-profile version of its GeForce RTX 5060 card. The RTX 5060 OC LP delivers all of the performance of a full-sized card, but in half the volume
In Part I, we discussed why Grab is investing in a data mesh, referred to as the Signals Marketplace within Grab, as part of our evolving data culture. We also explained how data certification aids teams in reliably reusing data across different domains. However, cultural change doesn’t occur through principles alone; it happens when tools reshape people’s daily behaviors. Therefore, it is crucial for us to develop effective platforms that integrate these practices.
This follow-up focuses on these platforms that make certification work at Grab:
Hubble – the central metadata management platform with a built-in certification engine.
Genchi – the data quality observability platform.
Data Contract Registry – the central service for managing data contracts.
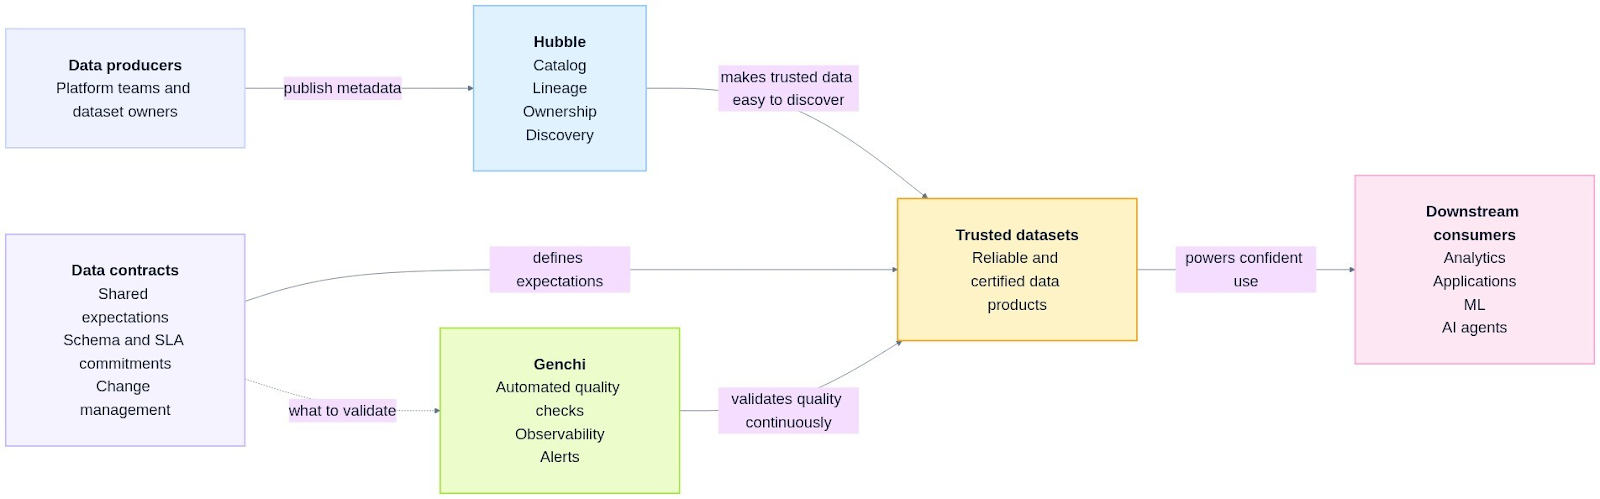
Together, these platforms turn data mesh principles into an operational system that scales across hundreds of thousands of datasets, streams, attributes, and metrics.
Hubble: The data discovery and governance layer
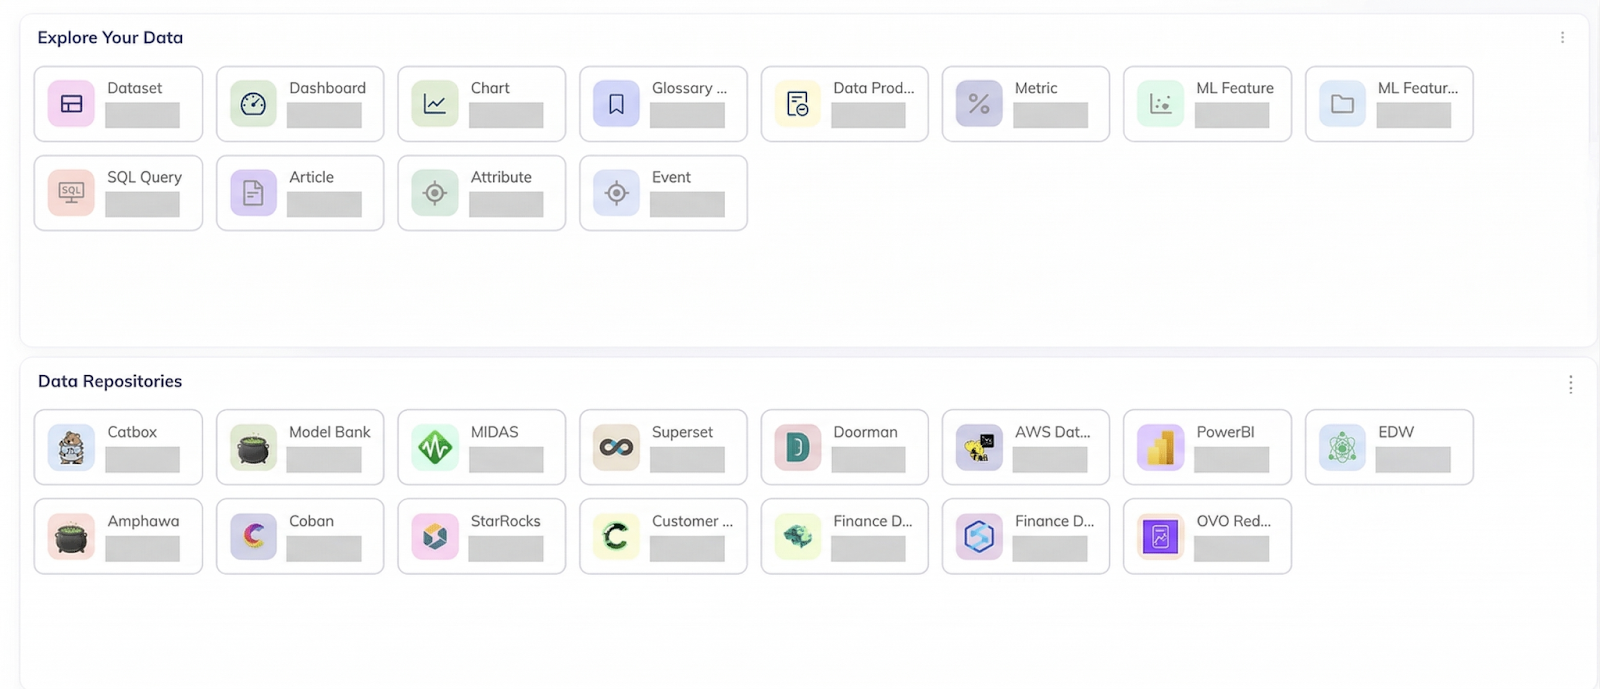
Hubble is Grab’s central metadata management platform and data catalog for all data assets, including datasets, dashboards, metrics, Machine learning (ML) models, and more. Built on top of the open‑source DataHub and heavily extended for Grab’s needs, it is the discovery and governance layer for the Signals Marketplace.
Figure 1. Hubble cataloging data assets across various data platforms in Grab.
What Hubble does for data mesh
For certification and data mesh, Hubble provides a few key capabilities:
Search and discovery: Data analysts/scientists, engineers, and product managers use Hubble to search the rich swath of data assets, then inspect schemas, documentation, lineage, and usage statistics in one place. This replaces back-channel questions and tribal knowledge with a single, self-serve catalog.
Ownership and domains: Every asset is tied to a domain and explicit technical and business owners. This enforces the domain ownership model that Signals Marketplace depends on. Producers are clearly accountable for the quality and lifecycle of the data products they publish.
Data contracts and documentation: Data contracts, classifications, and rich documentation live as structured metadata attached to each asset, not scattered across wikis and slide decks. Producers and consumers share the same source of truth when they ask questions like, “what does this table guarantee?”.
Lineage and impact analysis: Hubble provides table, column, and metric-level lineage so owners can see which teams and pipelines depend on their data before making breaking changes or deprecations. Instead of guessing, they can answer “what will I break?” with a single click.
Certification status: The familiar “Hubble green tick” turns trust into a first-class signal in the catalog. Assets that meet Grab’s certification criteria are clearly marked with a drill-down view of which criteria are satisfied (ownership, documentation, contracts, quality tests, upstream certification) and which are still missing.
From a consumer’s point of view, this collapses a lot of uncertainty into a simple workflow: search → filter to “certified” → pick the most suitable asset. They don’t need to reverse-engineer reliability from table names and hearsay.
Hubble’s system architecture
The open-source DataHub architecture is fundamentally event-driven and designed for high extensibility, moving away from the “passive” catalogs of the past, towards a “living” metadata graph. DataHub models everything as an Entity (e.g., a Dataset), composed of multiple Aspects (atomic versioned metadata like SchemaMetadata or Ownership), connected by Relationships (e.g., DownstreamOf).
Since introducing DataHub as Grab’s central data catalog in 2022, we’ve tailored it to Grab’s specific needs while continuously rebasing onto the latest open-source DataHub releases. This lets us adopt new capabilities from the community quickly, contribute improvements back, and evolve Hubble without forking away from the main project.
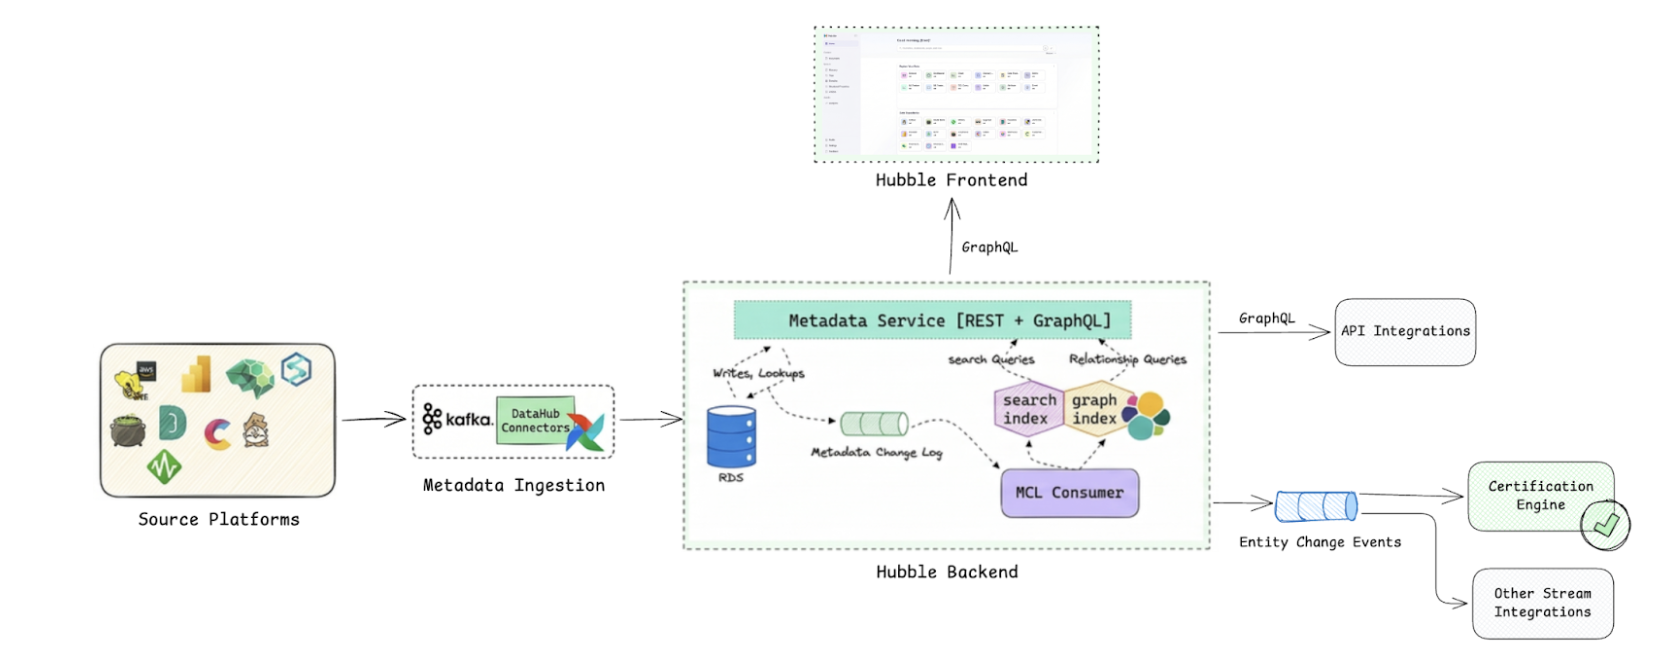
On top of the DataHub foundation, Hubble ingests metadata from Grab’s source platforms in two ways. Source systems either push changes as they happen, or Hubble periodically pulls metadata via Airflow jobs into the central metadata service that exposes GraphQL and REST APIs. Every change is then published to Kafka as metadata events (low-level change logs for indexers and audits, and higher-level semantic events for workflows), keeping Hubble’s search and lineage indices fresh and allowing downstream integrations like certification, deprecation notices, and governance automation to react to metadata changes in near real time.
This architecture is crucial for a data mesh because metadata evolves more rapidly than organizational changes. As domains change, tables are relocated, or pipelines are refactored, Hubble continuously updates, allowing certification to keep pace without the need for manual re-audits.
Figure 2. Hubble’s system architecture.
Computational certification via the certification engine on Hubble
A data asset’s certification state is not a manual label, it is computed by an event-driven certification engine built on the DataHub Actions framework. As source platforms for tables, streams, metrics, and user attributes push metadata into Hubble, every change becomes a metadata event. The engine subscribes to these events and re-evaluates the certification state of the data asset based on the predetermined certification criteria.
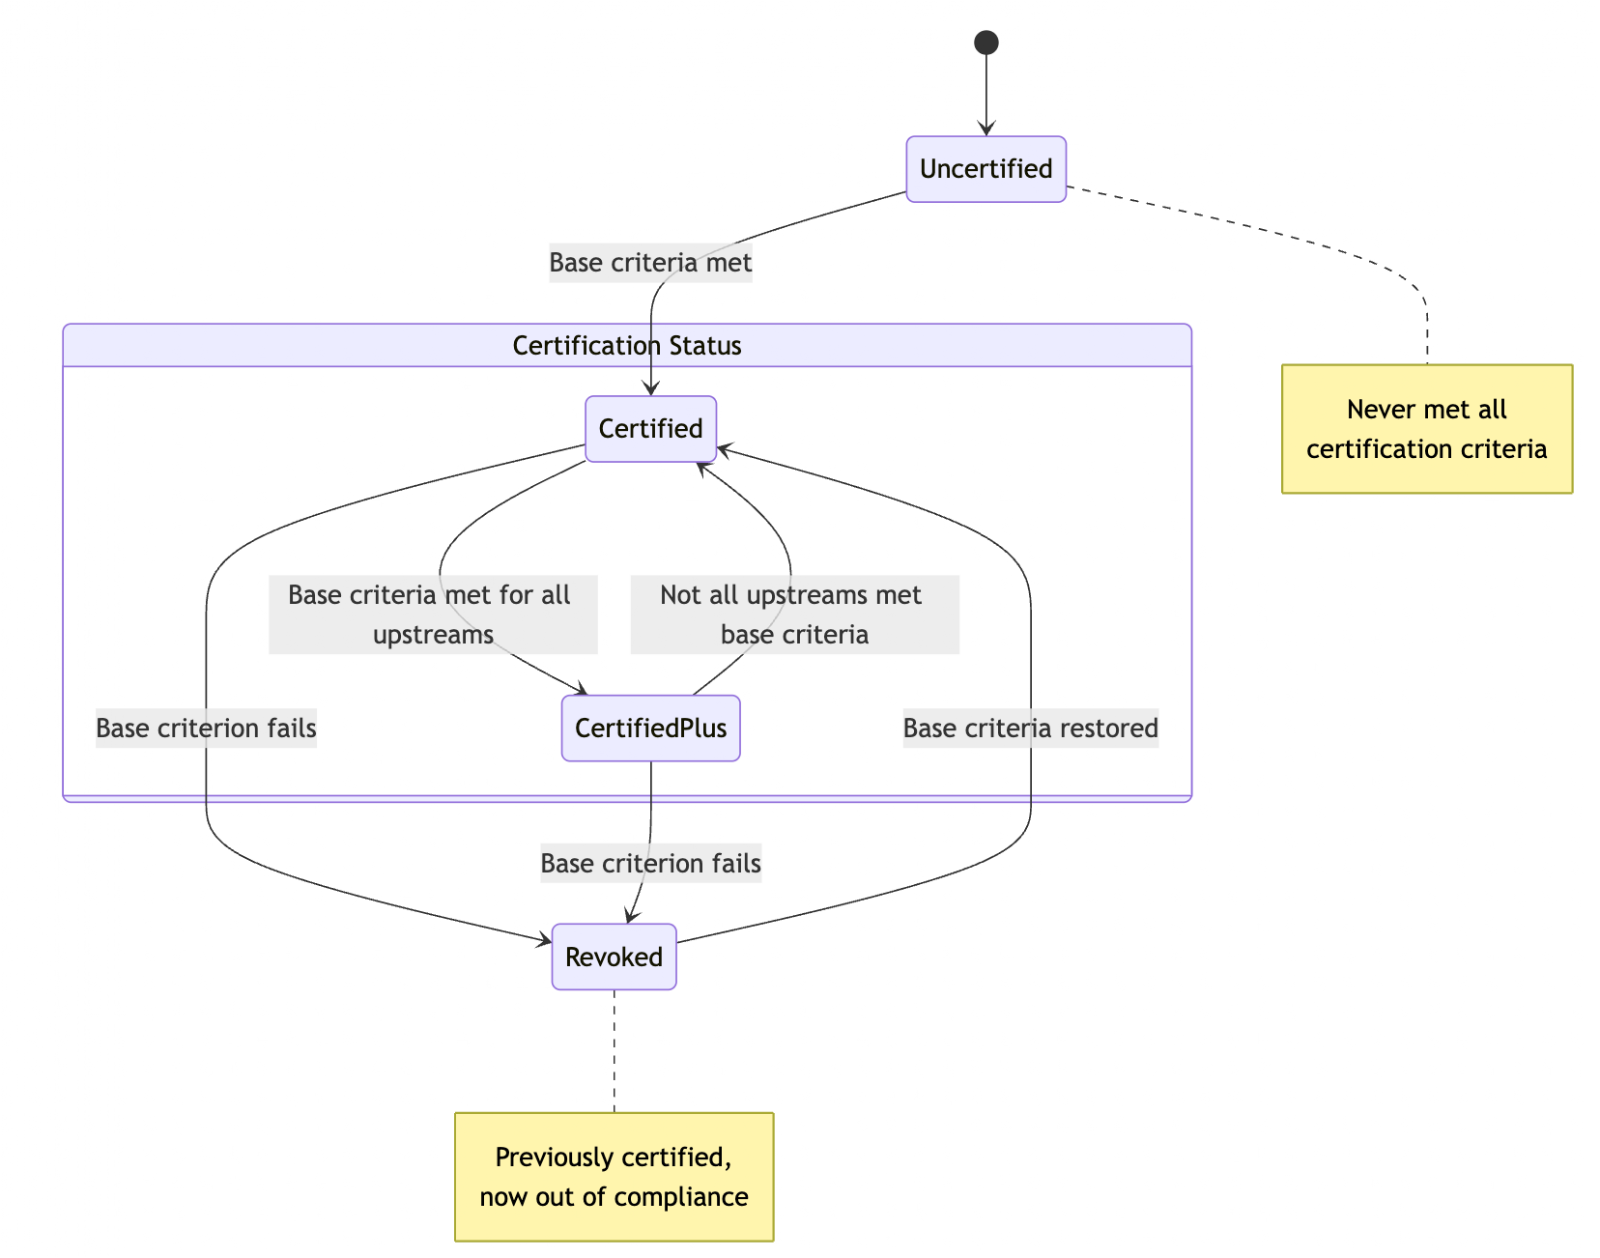
Conceptually, assets move between four states:
Uncertified: Never met all criteria.
Certified: Asset itself meets all required criteria.
CertifiedPlus: Stricter conditions than Certified, requiring both the asset and all of its upstreams to meet the criteria.
Revoked: Previously certified but now out of compliance.
The state diagram below captures how assets move between these states as metadata and upstream health change.
Figure 3. Certification state diagram.
While each asset type can add its own nuances (for example, metrics and attributes may also require explicit endorsement from business data owners), the core certification criteria are consistent:
Ownership and domain: Clear domain assignment plus accountable technical and business data owners.
Documentation and semantics: Table/metric documentation and, where relevant, column-level descriptions so consumers understand what the data means.
Lineage and upstream trust: For stronger levels like CertifiedPlus, upstream lineage must be present, and upstream assets must themselves be certified.
Contracts and runtime quality: Linked data contracts that spell out expectations, backed by required Genchi tests for freshness, volume/completeness, schema stability, and critical business checks.
Governance signals: No conflicting deprecation flags or policy violations (for example, missing required classifications on sensitive data).
If an asset satisfies the base criteria, the engine writes a certification aspect back into Hubble and surfaces it as a green tick; if the asset later falls out of compliance, certification is revoked, and downstream assets are re-evaluated as needed. This is because all certification changes are stored as time-series metadata and driven by events rather than a one-off checklist; certification becomes a continuous, metadata-driven process that keeps pace as the entity evolves.
Genchi: The data quality observability layer
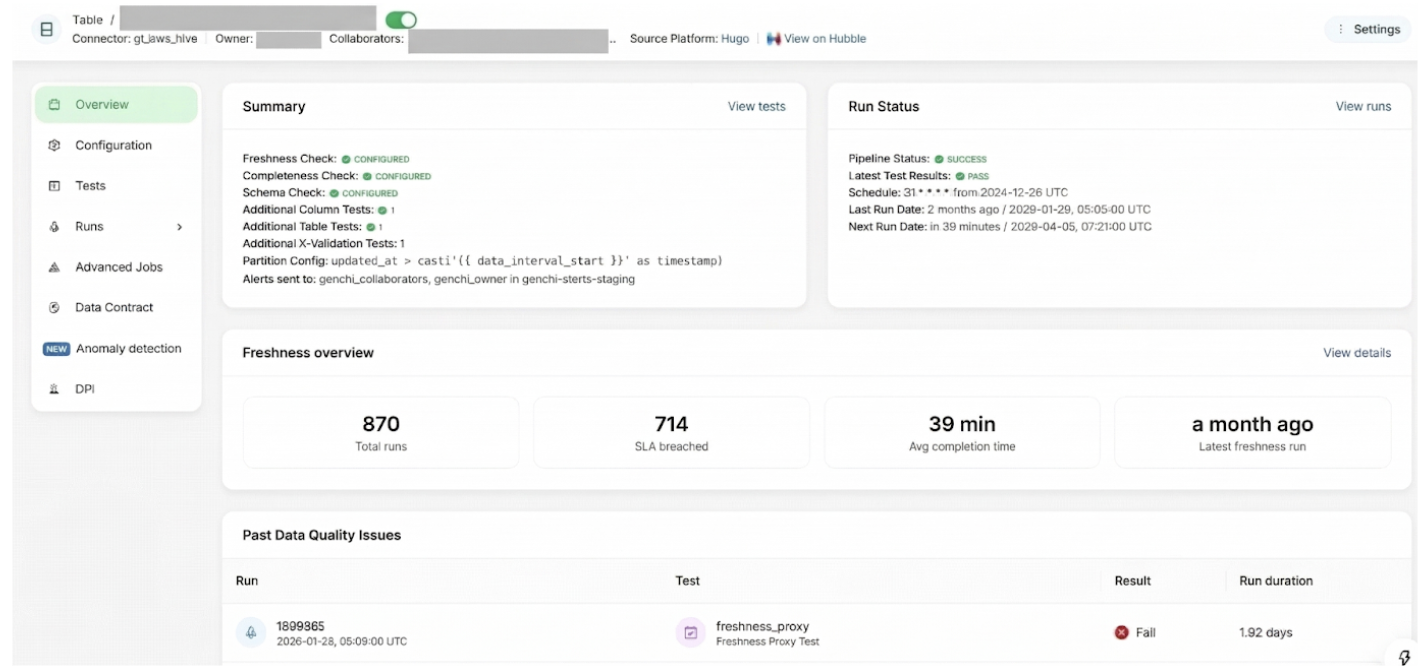
Genchi is Grab’s in-house, self-service data quality observability platform. It allows teams to define and run data quality tests on their datasets, receive alerts when something goes wrong, and integrate those tests directly into data contracts so that issues are caught and contained before they impact downstream consumers.
Figure 4. Genchi job configuration page, where dataset owners enroll a table and set up freshness, volume, schema, and other data quality tests for it.
What Genchi does for data mesh
In a data mesh, every domain is responsible for the quality of the data products it publishes. Genchi is the guardrail that makes that responsibility practical at scale. At its core, Genchi turns “good data” into clear, testable pillars that a data asset must satisfy:
Freshness and timeliness: Is the data recent enough to trust? Genchi runs data freshness and pipeline-freshness checks so owners know when today’s numbers are really “today’s” and can spot delayed loads before they hit dashboards or models.
Completeness and volume: Are we seeing all the records we expect? Volume and completeness tests compare current loads against historical baselines or source systems to flag partial backfills, silent drops, or suspicious spikes.
Structural stability (schema): Did the shape of the data change? Schema checks detect added/removed columns and type changes so that teams don’t discover breaking changes only after pipelines or reports start failing.
Semantic validity (values and business rules): Do the values themselves make sense? Column-level and X-Validation tests enforce constraints like uniqueness, ranges, patterns, cross-table reconciliations, and more advanced anomaly detection on row counts and null percentages.
Wrapped around these pillars is the operational layer:
Genchi runs these checks continuously (on schedule or on pipeline completion), emits real-time alerts, and helps teams drill into failing records and trends instead of debugging blind.
Its health signals flow into the catalog and incident tooling, so consumers see quality status alongside metadata and contract breaches are handled consistently.
The result is a mesh where domains publish data products with explicit, machine-enforced quality guarantees, and consumers can safely reuse them without a central team hand-holding every request.
Genchi’s system architecture
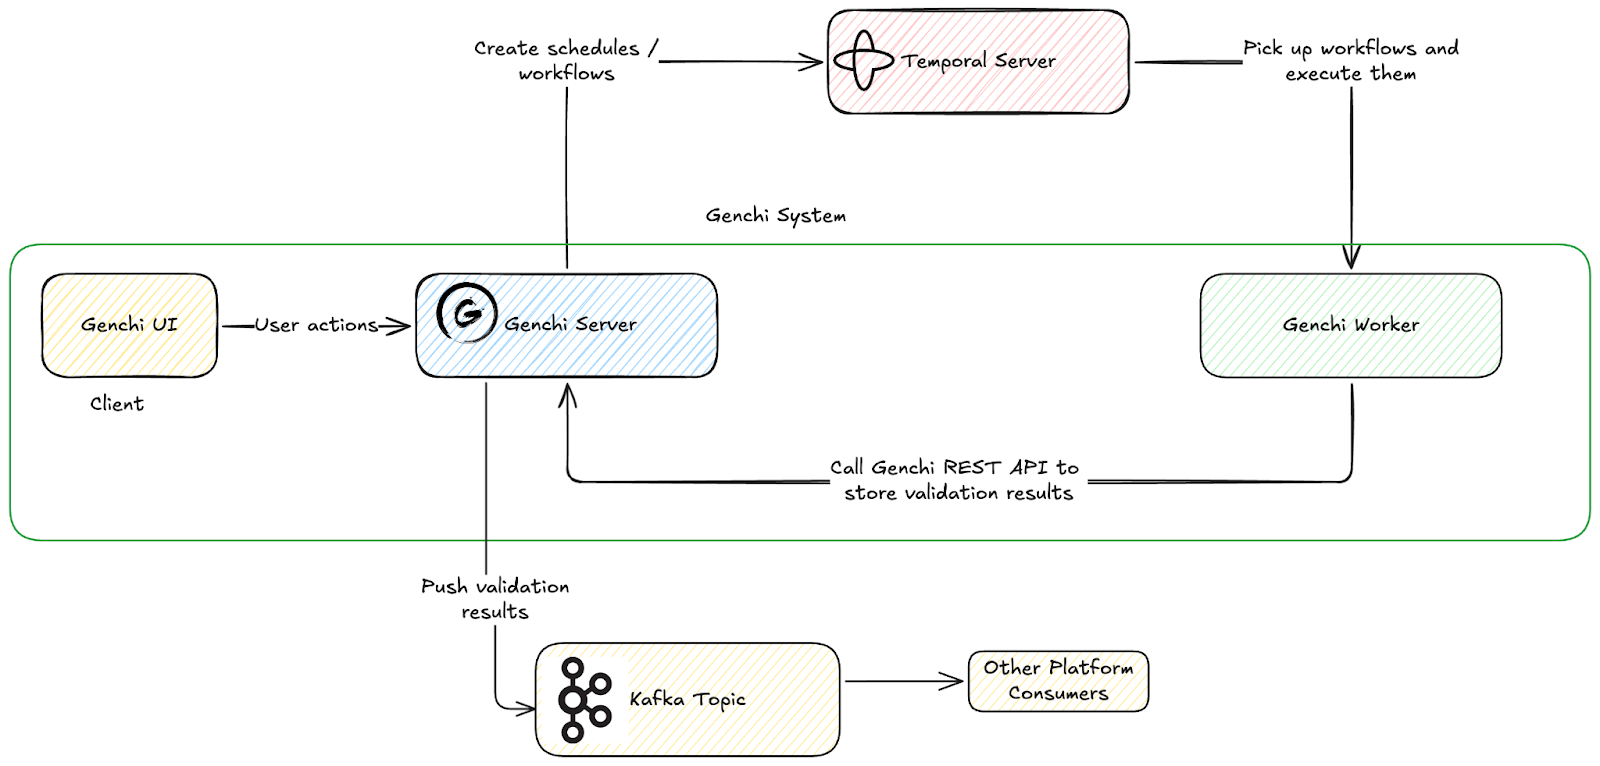
The Genchi system is designed to handle validation workflows triggered by user actions or automated schedules. It utilizes Temporal for reliable workflow orchestration and Kafka for event-driven data distribution to downstream consumers.
Figure 5. Genchi’s system architecture.
Triggering tests on pipeline completion with Sync with Pipeline (SWP)
Before SWP, Genchi tests lived on their own cron schedules, completely decoupled from the Airflow pipelines that actually produced the data. Teams had to manually copy pipeline crons into Genchi, juggle offset/lookback math to point at the “right” pipeline batch, and hope that nothing drifted over time. The result: misconfigured pipeline duration Service Level Agreement (SLA) checks, and tests sometimes running too early, too late, or against the wrong batch. This leads to noisy alerts and false-positive Data Production Issue (DPI).
To solve this, Genchi leans on Lighthouse, Grab’s pipeline execution and monitoring service. Lighthouse tracks when Airflow jobs start, finish, and which data interval they cover, and exposes that as structured execution events that the rest of the observability stack can consume.
SWP then flips Genchi from “best-effort cron alignment” to event-driven orchestration. Instead of guessing when a pipeline should have finished, Genchi listens to Lighthouse execution events. When a pipeline run is completed, Lighthouse emits an event with the run’s schedule and data interval; Genchi consumes that event, spins up an ad-hoc validation run aligned to that execution, and runs data-quality tests on the corresponding slice of data.
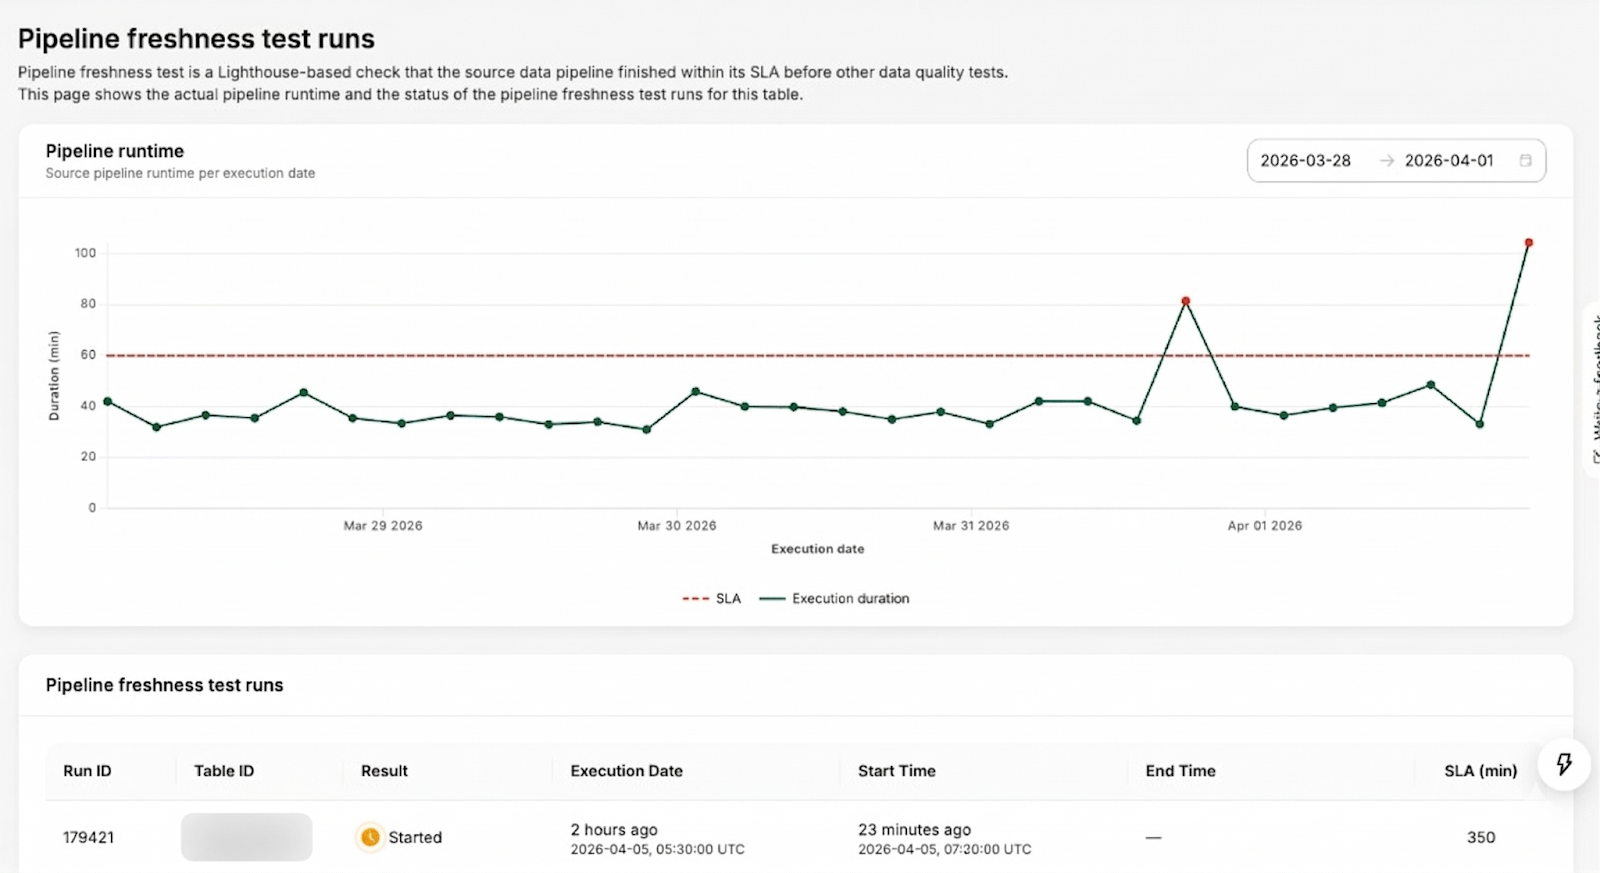
Pipeline-freshness is modeled as its own run type, separate from the data-quality tests that run on pipeline completion. Instead of inspecting rows, it is triggered asynchronously on the same schedule as the pipeline and tracks when each run actually completes in Lighthouse. This gives data producers an intuitive way to get alerted when a pipeline exceeds its expected runtime, and to review historical runtime behavior for any drift over time.
In practice, this makes test orchestration both simpler and more trustworthy. Users no longer need to think about crons or offsets for their data validation jobs. “Run after my pipeline finishes” becomes the default, with advanced overrides for custom schedules when needed. Misconfigured freshness tests and noisy DPIs drop, because Genchi is now anchored to real pipeline execution signals rather than approximations.
Figure 6. Genchi pipeline-freshness run page for a table, showing the historical runtime patterns and the SLA status.
Data Contract Registry: The producer–consumer agreement layer
At Grab, a data contract is the explicit, versioned agreement between a producer and its consumers that defines the data’s shape and semantics, the quality and availability guarantees around it, and the rules for how and for how long it may be used. The Data Contract Registry is the source of truth for these agreements, while Genchi and platform-specific observability stacks continuously verify that reality still matches what the contract promises.
What Data Contract Registry does for data mesh
Within Grab’s data mesh, the Data Contract Registry is the producer–consumer agreement layer: it centralizes contracts for key assets (data lake tables, Kafka streams, metrics) so expectations on shape, quality, SLAs, and lifecycle live in one canonical place instead of being scattered across individual platforms. That single source of truth underpins Hubble certification (only assets with valid contracts can be certified), gives Kinabalu (Grab’s central incident lifecycle orchestrator) the context it needs to open and route DPIs when checks fail, and lets Ouroboros (a table lifecycle management tool) interpret lifecycle clauses consistently.
This is important for a data mesh because it transforms the concept of “data as a product” from a mere slogan into an operational reality. Contracts provide domain teams with a clear and enforceable method to specify their guarantees, offering consumers a solid foundation for trust and data reuse across domains. Importantly, a contract is only valuable if its promises are verifiable and enforceable. Schema expectations, quality checks, and SLAs are all connected to concrete tests and health endpoints, enabling downstream platforms to automatically detect breaches and manage or mitigate breaking changes, rather than treating the contract as static documentation.
On top of storing contracts, the registry also manages contract changes. When a contract evolves, say a schema tweak, a new freshness SLA, or a planned deprecation, it identifies the right stakeholders (direct downstream owners, heavy query users, and, for critical assets, deeper dependencies) and pushes targeted Slack notifications. Producers get a structured way to roll out changes safely while consumers get timely, actionable signals instead of surprise breakages so that both enforcement and change management are baked into the mesh.
In addition to storing contracts, the registry also manages contract changes. When a contract evolves such as a schema adjustment, a new freshness SLA, or a planned deprecation, it identifies the appropriate stakeholder (direct downstream owners, heavy query users, and critical assets with deeper dependencies) and then sends targeted Slack notifications to these stakeholders. This process provides producers with a structured method to implement changes safely, while consumers receive timely and actionable alerts, preventing unexpected disruptions. As a result, both enforcement and change management are seamlessly integrated into the data mesh.
The data contract specification
Under the hood, a data contract in the registry is a JSON construct that follows the contract specification. Grab’s data contract specification is inspired by the public Data Contract Specification, but adapted to our environment so that contracts plug directly into our observability stack and automated incident management workflows.
Notably, we embed data health and test health URLs in the contract itself. Each data-quality rule points to a concrete health endpoint, so Kinabalu can determine contract breaches and create DPIs by calling those test health URLs, without hard-coding what “healthy” means. For example, a completeness test on the latest partition can be marked healthy only if the last N days are complete, not just because the most recent test run happened to pass. The data health URL at the contract root then lets Kinabalu fetch the overall diagnosis and decide who the DPI should be assigned to. More on this will be covered in Part III.
Here’s a simplified example of a contract for a data-lake table:
{"specification_version":1,"asset_urn":"urn:li:dataset:(urn:li:dataPlatform:hive,genchi.validation_jobs,PROD)","entity_type":"datalake_table","health_url":"https://example-hugo.grab.com/assets/genchi.validation_jobs/health","contract_details":{"contact":{"oncall_group":"oncall-genchi","slack_channel":"ask-genchi"},"terms":{"usage":"Source of truth for all genchi validation jobs.","limitations":"Not suitable for real-time use cases.","notice_period_in_days":14},"schema":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_schema_test/health","uid":"fundamental_schema_test","version":1}],"sla":{"freshness":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_freshness_test/health","uid":"fundamental_freshness_test","version":1}],"lifecycle":null},"data_quality":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_completeness_test/health","uid":"fundamental_completeness_test","version":1}]}}
The contract in the registry only stores references to enforceable rules, which are an identifier and version, like the example above, rather than the full configuration body. This keeps contracts lightweight and tool-agnostic, while giving rule-enforcement tools (Genchi for data-quality tests, Ouroboros for table lifecycle) and Kinabalu a stable handle to resolve the actual rule definition in their own systems, without duplicating configuration or letting it drift across platforms.
Conclusion
By bringing Hubble, Genchi, and the Data Contract Registry together, we provide the foundational tools to build trust in certified data assets. Hubble enables discovery and establishes domains and ownership; the Data Contract Registry captures explicit expectations between producers and consumers; and Genchi continuously validates those promises with tests on freshness, volume, schema, and business rules. Hubble’s certification engine then evaluates these ownership, contract, and quality signals to decide whether an asset meets Grab’s standards and surfaces that as a visible certification state. As a result, consumers can confidently default to certified assets, usage converges on a smaller, better-governed pool of datasets, and certification becomes a mechanism that changes producer behavior and guides consumer choice. We saw this convergence in practice. In just one year since the Signals Marketplace campaign began in 2024, the number of P80 datasets (the most used tables that account for 80% of all queries) has dropped by over 58%.
This data foundation is especially important in an AI-first future for Grab. Certified streams, tables, metrics, and attributes give AI agents and automated analytics a default substrate they can rely on. With Hubble and Genchi, data producers have clear ownership, contracts, and observability. Data consumers can discover and trust certified assets without guesswork, and platform teams can measure and improve Signals Marketplace health over time (for example, queries on certified assets, lineage depth, and cost). Together, these capabilities turn “data mesh” from a slogan into an operational, AI-ready marketplace of reliable, reusable signals that power decisions across Grab.
Figure 7. Building trust in certified data assets through discovery, contracts, and continuous validation.
What’s next
In the next blog, we’ll zoom into the DPI process itself with Kinabalu as the incident lifecycle orchestrator:
How Genchi test failures and data contract breaches turn into DPIs.
How DPI is assigned based on root causes and what sets the priority level.
The patterns we’ve seen in “noisy” vs actionable DPIs, and what we’ve changed in our platforms.
How we’re using automation and agents to reduce DPI toil and close the loop back into certification.
We’ll walk through concrete case studies showing how a single broken table moves from first failure, to diagnosis and fix, to updated contracts and a more resilient certified data asset.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
In Part I, we discussed why Grab is investing in a data mesh, referred to as the Signals Marketplace within Grab, as part of our evolving data culture. We also explained how data certification aids teams in reliably reusing data across different domains. However, cultural change doesn’t occur through principles alone; it happens when tools reshape people’s daily behaviors. Therefore, it is crucial for us to develop effective platforms that integrate these practices.
This follow-up focuses on these platforms that make certification work at Grab:
Hubble – the central metadata management platform with a built-in certification engine.
Genchi – the data quality observability platform.
Data Contract Registry – the central service for managing data contracts.
Together, these platforms turn data mesh principles into an operational system that scales across hundreds of thousands of datasets, streams, attributes, and metrics.
Hubble: The data discovery and governance layer
Hubble is Grab’s central metadata management platform and data catalog for all data assets, including datasets, dashboards, metrics, Machine learning (ML) models, and more. Built on top of the open‑source DataHub and heavily extended for Grab’s needs, it is the discovery and governance layer for the Signals Marketplace.
Figure 1. Hubble cataloging data assets across various data platforms in Grab.
What Hubble does for data mesh
For certification and data mesh, Hubble provides a few key capabilities:
Search and discovery: Data analysts/scientists, engineers, and product managers use Hubble to search the rich swath of data assets, then inspect schemas, documentation, lineage, and usage statistics in one place. This replaces back-channel questions and tribal knowledge with a single, self-serve catalog.
Ownership and domains: Every asset is tied to a domain and explicit technical and business owners. This enforces the domain ownership model that Signals Marketplace depends on. Producers are clearly accountable for the quality and lifecycle of the data products they publish.
Data contracts and documentation: Data contracts, classifications, and rich documentation live as structured metadata attached to each asset, not scattered across wikis and slide decks. Producers and consumers share the same source of truth when they ask questions like, “what does this table guarantee?”.
Lineage and impact analysis: Hubble provides table, column, and metric-level lineage so owners can see which teams and pipelines depend on their data before making breaking changes or deprecations. Instead of guessing, they can answer “what will I break?” with a single click.
Certification status: The familiar “Hubble green tick” turns trust into a first-class signal in the catalog. Assets that meet Grab’s certification criteria are clearly marked with a drill-down view of which criteria are satisfied (ownership, documentation, contracts, quality tests, upstream certification) and which are still missing.
From a consumer’s point of view, this collapses a lot of uncertainty into a simple workflow: search → filter to “certified” → pick the most suitable asset. They don’t need to reverse-engineer reliability from table names and hearsay.
Hubble’s system architecture
The open-source DataHub architecture is fundamentally event-driven and designed for high extensibility, moving away from the “passive” catalogs of the past, towards a “living” metadata graph. DataHub models everything as an Entity (e.g., a Dataset), composed of multiple Aspects (atomic versioned metadata like SchemaMetadata or Ownership), connected by Relationships (e.g., DownstreamOf).
Since introducing DataHub as Grab’s central data catalog in 2022, we’ve tailored it to Grab’s specific needs while continuously rebasing onto the latest open-source DataHub releases. This lets us adopt new capabilities from the community quickly, contribute improvements back, and evolve Hubble without forking away from the main project.
On top of the DataHub foundation, Hubble ingests metadata from Grab’s source platforms in two ways. Source systems either push changes as they happen, or Hubble periodically pulls metadata via Airflow jobs into the central metadata service that exposes GraphQL and REST APIs. Every change is then published to Kafka as metadata events (low-level change logs for indexers and audits, and higher-level semantic events for workflows), keeping Hubble’s search and lineage indices fresh and allowing downstream integrations like certification, deprecation notices, and governance automation to react to metadata changes in near real time.
This architecture is crucial for a data mesh because metadata evolves more rapidly than organizational changes. As domains change, tables are relocated, or pipelines are refactored, Hubble continuously updates, allowing certification to keep pace without the need for manual re-audits.
Figure 2. Hubble’s system architecture.
Computational certification via the certification engine on Hubble
A data asset’s certification state is not a manual label, it is computed by an event-driven certification engine built on the DataHub Actions framework. As source platforms for tables, streams, metrics, and user attributes push metadata into Hubble, every change becomes a metadata event. The engine subscribes to these events and re-evaluates the certification state of the data asset based on the predetermined certification criteria.
Conceptually, assets move between four states:
Uncertified: Never met all criteria.
Certified: Asset itself meets all required criteria.
CertifiedPlus: Stricter conditions than Certified, requiring both the asset and all of its upstreams to meet the criteria.
Revoked: Previously certified but now out of compliance.
The state diagram below captures how assets move between these states as metadata and upstream health change.
Figure 3. Certification state diagram.
While each asset type can add its own nuances (for example, metrics and attributes may also require explicit endorsement from business data owners), the core certification criteria are consistent:
Ownership and domain: Clear domain assignment plus accountable technical and business data owners.
Documentation and semantics: Table/metric documentation and, where relevant, column-level descriptions so consumers understand what the data means.
Lineage and upstream trust: For stronger levels like CertifiedPlus, upstream lineage must be present, and upstream assets must themselves be certified.
Contracts and runtime quality: Linked data contracts that spell out expectations, backed by required Genchi tests for freshness, volume/completeness, schema stability, and critical business checks.
Governance signals: No conflicting deprecation flags or policy violations (for example, missing required classifications on sensitive data).
If an asset satisfies the base criteria, the engine writes a certification aspect back into Hubble and surfaces it as a green tick; if the asset later falls out of compliance, certification is revoked, and downstream assets are re-evaluated as needed. This is because all certification changes are stored as time-series metadata and driven by events rather than a one-off checklist; certification becomes a continuous, metadata-driven process that keeps pace as the entity evolves.
Genchi: The data quality observability layer
Genchi is Grab’s in-house, self-service data quality observability platform. It allows teams to define and run data quality tests on their datasets, receive alerts when something goes wrong, and integrate those tests directly into data contracts so that issues are caught and contained before they impact downstream consumers.
Figure 4. Genchi job configuration page, where dataset owners enroll a table and set up freshness, volume, schema, and other data quality tests for it.
What Genchi does for data mesh
In a data mesh, every domain is responsible for the quality of the data products it publishes. Genchi is the guardrail that makes that responsibility practical at scale. At its core, Genchi turns “good data” into clear, testable pillars that a data asset must satisfy:
Freshness and timeliness: Is the data recent enough to trust? Genchi runs data freshness and pipeline-freshness checks so owners know when today’s numbers are really “today’s” and can spot delayed loads before they hit dashboards or models.
Completeness and volume: Are we seeing all the records we expect? Volume and completeness tests compare current loads against historical baselines or source systems to flag partial backfills, silent drops, or suspicious spikes.
Structural stability (schema): Did the shape of the data change? Schema checks detect added/removed columns and type changes so that teams don’t discover breaking changes only after pipelines or reports start failing.
Semantic validity (values and business rules): Do the values themselves make sense? Column-level and X-Validation tests enforce constraints like uniqueness, ranges, patterns, cross-table reconciliations, and more advanced anomaly detection on row counts and null percentages.
Wrapped around these pillars is the operational layer:
Genchi runs these checks continuously (on schedule or on pipeline completion), emits real-time alerts, and helps teams drill into failing records and trends instead of debugging blind.
Its health signals flow into the catalog and incident tooling, so consumers see quality status alongside metadata and contract breaches are handled consistently.
The result is a mesh where domains publish data products with explicit, machine-enforced quality guarantees, and consumers can safely reuse them without a central team hand-holding every request.
Genchi’s system architecture
The Genchi system is designed to handle validation workflows triggered by user actions or automated schedules. It utilizes Temporal for reliable workflow orchestration and Kafka for event-driven data distribution to downstream consumers.
Figure 5. Genchi’s system architecture.
Triggering tests on pipeline completion with Sync with Pipeline (SWP)
Before SWP, Genchi tests lived on their own cron schedules, completely decoupled from the Airflow pipelines that actually produced the data. Teams had to manually copy pipeline crons into Genchi, juggle offset/lookback math to point at the “right” pipeline batch, and hope that nothing drifted over time. The result: misconfigured pipeline duration Service Level Agreement (SLA) checks, and tests sometimes running too early, too late, or against the wrong batch. This leads to noisy alerts and false-positive Data Production Issue (DPI).
To solve this, Genchi leans on Lighthouse, Grab’s pipeline execution and monitoring service. Lighthouse tracks when Airflow jobs start, finish, and which data interval they cover, and exposes that as structured execution events that the rest of the observability stack can consume.
SWP then flips Genchi from “best-effort cron alignment” to event-driven orchestration. Instead of guessing when a pipeline should have finished, Genchi listens to Lighthouse execution events. When a pipeline run is completed, Lighthouse emits an event with the run’s schedule and data interval; Genchi consumes that event, spins up an ad-hoc validation run aligned to that execution, and runs data-quality tests on the corresponding slice of data.
Pipeline-freshness is modeled as its own run type, separate from the data-quality tests that run on pipeline completion. Instead of inspecting rows, it is triggered asynchronously on the same schedule as the pipeline and tracks when each run actually completes in Lighthouse. This gives data producers an intuitive way to get alerted when a pipeline exceeds its expected runtime, and to review historical runtime behavior for any drift over time.
In practice, this makes test orchestration both simpler and more trustworthy. Users no longer need to think about crons or offsets for their data validation jobs. “Run after my pipeline finishes” becomes the default, with advanced overrides for custom schedules when needed. Misconfigured freshness tests and noisy DPIs drop, because Genchi is now anchored to real pipeline execution signals rather than approximations.
Figure 6. Genchi pipeline-freshness run page for a table, showing the historical runtime patterns and the SLA status.
Data Contract Registry: The producer–consumer agreement layer
At Grab, a data contract is the explicit, versioned agreement between a producer and its consumers that defines the data’s shape and semantics, the quality and availability guarantees around it, and the rules for how and for how long it may be used. The Data Contract Registry is the source of truth for these agreements, while Genchi and platform-specific observability stacks continuously verify that reality still matches what the contract promises.
What Data Contract Registry does for data mesh
Within Grab’s data mesh, the Data Contract Registry is the producer–consumer agreement layer: it centralizes contracts for key assets (data lake tables, Kafka streams, metrics) so expectations on shape, quality, SLAs, and lifecycle live in one canonical place instead of being scattered across individual platforms. That single source of truth underpins Hubble certification (only assets with valid contracts can be certified), gives Kinabalu (Grab’s central incident lifecycle orchestrator) the context it needs to open and route DPIs when checks fail, and lets Ouroboros (a table lifecycle management tool) interpret lifecycle clauses consistently.
This is important for a data mesh because it transforms the concept of “data as a product” from a mere slogan into an operational reality. Contracts provide domain teams with a clear and enforceable method to specify their guarantees, offering consumers a solid foundation for trust and data reuse across domains. Importantly, a contract is only valuable if its promises are verifiable and enforceable. Schema expectations, quality checks, and SLAs are all connected to concrete tests and health endpoints, enabling downstream platforms to automatically detect breaches and manage or mitigate breaking changes, rather than treating the contract as static documentation.
On top of storing contracts, the registry also manages contract changes. When a contract evolves, say a schema tweak, a new freshness SLA, or a planned deprecation, it identifies the right stakeholders (direct downstream owners, heavy query users, and, for critical assets, deeper dependencies) and pushes targeted Slack notifications. Producers get a structured way to roll out changes safely while consumers get timely, actionable signals instead of surprise breakages so that both enforcement and change management are baked into the mesh.
In addition to storing contracts, the registry also manages contract changes. When a contract evolves such as a schema adjustment, a new freshness SLA, or a planned deprecation, it identifies the appropriate stakeholder (direct downstream owners, heavy query users, and critical assets with deeper dependencies) and then sends targeted Slack notifications to these stakeholders. This process provides producers with a structured method to implement changes safely, while consumers receive timely and actionable alerts, preventing unexpected disruptions. As a result, both enforcement and change management are seamlessly integrated into the data mesh.
The data contract specification
Under the hood, a data contract in the registry is a JSON construct that follows the contract specification. Grab’s data contract specification is inspired by the public Data Contract Specification, but adapted to our environment so that contracts plug directly into our observability stack and automated incident management workflows.
Notably, we embed data health and test health URLs in the contract itself. Each data-quality rule points to a concrete health endpoint, so Kinabalu can determine contract breaches and create DPIs by calling those test health URLs, without hard-coding what “healthy” means. For example, a completeness test on the latest partition can be marked healthy only if the last N days are complete, not just because the most recent test run happened to pass. The data health URL at the contract root then lets Kinabalu fetch the overall diagnosis and decide who the DPI should be assigned to. More on this will be covered in Part III.
Here’s a simplified example of a contract for a data-lake table:
{"specification_version":1,"asset_urn":"urn:li:dataset:(urn:li:dataPlatform:hive,genchi.validation_jobs,PROD)","entity_type":"datalake_table","health_url":"https://example-hugo.grab.com/assets/genchi.validation_jobs/health","contract_details":{"contact":{"oncall_group":"oncall-genchi","slack_channel":"ask-genchi"},"terms":{"usage":"Source of truth for all genchi validation jobs.","limitations":"Not suitable for real-time use cases.","notice_period_in_days":14},"schema":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_schema_test/health","uid":"fundamental_schema_test","version":1}],"sla":{"freshness":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_freshness_test/health","uid":"fundamental_freshness_test","version":1}],"lifecycle":null},"data_quality":[{"type":"genchi","health_url":"https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_completeness_test/health","uid":"fundamental_completeness_test","version":1}]}}
The contract in the registry only stores references to enforceable rules, which are an identifier and version, like the example above, rather than the full configuration body. This keeps contracts lightweight and tool-agnostic, while giving rule-enforcement tools (Genchi for data-quality tests, Ouroboros for table lifecycle) and Kinabalu a stable handle to resolve the actual rule definition in their own systems, without duplicating configuration or letting it drift across platforms.
Conclusion
By bringing Hubble, Genchi, and the Data Contract Registry together, we provide the foundational tools to build trust in certified data assets. Hubble enables discovery and establishes domains and ownership; the Data Contract Registry captures explicit expectations between producers and consumers; and Genchi continuously validates those promises with tests on freshness, volume, schema, and business rules. Hubble’s certification engine then evaluates these ownership, contract, and quality signals to decide whether an asset meets Grab’s standards and surfaces that as a visible certification state. As a result, consumers can confidently default to certified assets, usage converges on a smaller, better-governed pool of datasets, and certification becomes a mechanism that changes producer behavior and guides consumer choice. We saw this convergence in practice. In just one year since the Signals Marketplace campaign began in 2024, the number of P80 datasets (the most used tables that account for 80% of all queries) has dropped by over 58%.
This data foundation is especially important in an AI-first future for Grab. Certified streams, tables, metrics, and attributes give AI agents and automated analytics a default substrate they can rely on. With Hubble and Genchi, data producers have clear ownership, contracts, and observability. Data consumers can discover and trust certified assets without guesswork, and platform teams can measure and improve Signals Marketplace health over time (for example, queries on certified assets, lineage depth, and cost). Together, these capabilities turn “data mesh” from a slogan into an operational, AI-ready marketplace of reliable, reusable signals that power decisions across Grab.
Figure 7. Building trust in certified data assets through discovery, contracts, and continuous validation.
What’s next
In the next blog, we’ll zoom into the DPI process itself with Kinabalu as the incident lifecycle orchestrator:
How Genchi test failures and data contract breaches turn into DPIs.
How DPI is assigned based on root causes and what sets the priority level.
The patterns we’ve seen in “noisy” vs actionable DPIs, and what we’ve changed in our platforms.
How we’re using automation and agents to reduce DPI toil and close the loop back into certification.
We’ll walk through concrete case studies showing how a single broken table moves from first failure, to diagnosis and fix, to updated contracts and a more resilient certified data asset.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Security analysis firm Xint has disclosed a security bug in the Linux kernel
that allows for arbitrary 4-byte writes to the page cache, and which has been
present since 2017.
The vulnerability has
been fixed in mainline kernels. A
proof-of-concept script demonstrates how to use the flaw to corrupt a setuid
binary, which works on
multiple distributions, by requesting an AEAD-encrypted socket from user space
and splicing a particular payload into it.
A supplemental blog
post gives more details about the discovery and remediation.
A core primitive underlying this bug is splice(): it transfers data between file
descriptors and pipes without copying, passing page cache pages by reference.
When a user splices a file into a pipe and then into an AF_ALG socket, the
socket’s input scatterlist holds direct references to the kernel’s cached pages
of that file. The pages are not duplicated; the scatterlist entries point at the
same physical pages that back every read(), mmap(), and execve() of that file.
At this year’s Gartner Security and Risk Management Summit in Sydney, Rapid7 CISO Brian Castagna joined industry CISO Nigel Hedges for a fireside chat on the decisions security leaders are actually making right now. They discussed the real decisions being made right now about budgets, burnout, AI, and perspective on consolidation.
The conversation reinforced what we see across many organizations: SecOps is very much focused on protecting business resilience, enabling confident decisions by senior security leaders, and building programs that scale across people, platforms, and emerging technology. Let’s now take a look at some of the main highlights from this year’s Summit.
The business case for SecOps has shifted and boards are listening
The ‘invest in security or get breached’ pitch has run its course. Boards have heard it too many times; plus, it frames security as a cost center that only proves its value when something goes wrong.
We’re seeing it being replaced by a resilience narrative. In most incidents, the biggest business impact is operational disruption. Hours or days of downtime create immediate revenue loss, reputational damage, and perhaps worse still for some, regulatory exposure. CISOs who can connect their programs to that reality – translating incident data into business availability and financial risk – find it significantly easier to justify spend and shape investment decisions.
That shift in dynamic changes what gets measured and prioritized as well as how security leaders communicate upward to the board. Threat intelligence and kill chains still matter inside the SOC, but the ability to translate that to a clear risk narrative is fast becoming a leadership requirement in its own right.
Platform consolidation is growing, but it’s not binary
The platform-vs-best-of-breed debate was notably pragmatic. The real question is how to strike the right balance: Consolidate where it improves efficiency and visibility, retain point solutions where they materially reduce a specific risk.
On the ground, budget pressure has accelerated this. Fewer vendors, more integrated telemetry, and clearer operational ownership help make spend more defensible. The discussion framed consolidation through the lens of ‘control planes’ (endpoint, gateway, network), with shared telemetry as the connective layer.
A real-world example grounded the conversation: Build a global security program for a 5,000-person organization across 40 countries on a $3 million budget, using a selective mix of MDR, PAM, EPM, and targeted point solutions only where necessary. Throughout, the operating principle was simple in that every security investment needs to answer one question: What risk does this reduce, and importantly, what business outcome does it protect?
People remain the most difficult element of SecOps
Technology and process can be engineered, but people? They’re much harder. That was one of the most practical observations from the session, and it resonated with every security leader in the room.
The challenge goes beyond hiring technical talent to ensure organizations are building teams with the right mix of communication skills, cognitive diversity, motivation, and endurance. A common gap seen in the SOC is that many teams are strong technically but few can articulate risk effectively to executives. That matters because the value of SecOps increasingly depends on how well teams connect activity to impact.
At the same time, burnout remains a structural issue. When experienced analysts leave, institutional knowledge leaves with them. And no tool can replace that. For leaders, this reinforces the point that people strategy is core to the overall security strategy.
AI in SecOps is getting very real, and very practical
After a long hype cycle, the AI conversation is now far more grounded. The most credible use cases in SecOps are about helping teams manage volume, reduce noise, and move faster with better context.
The examples discussed in the session were telling: alert-assisted triage, natural-language log querying, incident summarisation, first-draft executive communications, and eventually more automated investigation workflows. The framing that landed best was AI as a ‘sidearm partner’; a force multiplier for experienced practitioners, rather than a substitute for judgment.
That distinction matters as human judgment is essential. But AI is becoming increasingly valuable for understaffed teams trying to scale operations and preserve the institutional knowledge that walks out the door when analysts move on.
Governing agentic AI begins with foundations you should already have
As the discussion turned to agentic AI, the focus centred on how more autonomous AI systems do introduce new governance questions, but many of the relevant controls already exist within mature security programs. Segmentation, least privilege, access management, and strong architectural boundaries remain the core defenses.
One analogy stuck: Just as graphite rods slow a nuclear chain reaction, controls like network segmentation and access boundaries can contain and constrain agentic behavior. The organizations best positioned for AI governance are often the ones that have already invested in zero trust principles and sound identity controls.
That reframes the conversation. AI governance isn’t a separate discipline, it’s the extension of existing security foundations into how AI systems behave, access data, and operate within defined boundaries.
What this means for the road ahead
If there was a unifying message, it was that the modern SecOps mandate is bigger than prevention. The industry has, to some extent, over-rotated on stopping threats and under-invested in resilience.
Security leaders require programs that communicate risk in business terms, make smart technology trade-offs, support their people, and adopt AI in ways that are practical and governable. The organizations that get this right will be the ones building strong foundations and using the right mix of platform, process, and intelligence to move faster and more confidently. Rapid7 is committed to being a partner to organizations looking to gain that confidence. Our exposure-informed MDR service empowers teams to adopt a more preemptive security posture by rapidly identifying high-impact exposures that could be imminent breach targets. Teams can also leverage expanded capabilities in data security posture management (DSPM) and compliance to help fortify assessment, prioritization, and response capabilities so they can further preempt attacks across the modern attack surface.
On April 28, 2026, cPanel issued a security update to fix a critical vulnerability affecting the cPanel & WHM and WP Squared products. In the cPanel release notes, the bug was described as “an issue with session loading and saving.” CVE-2026-41940, the identifier subsequently assigned on April 29, 2026, has a CVSS score of 9.8 and allows unauthenticated remote attackers to bypass authentication and gain unauthorized administrative access to the affected systems. First-party cPanel & WHM and WP Squared vendor advisories are available.
cPanel & WHM is web hosting control panel software used to manage websites and servers. WHM provides root-level administration, while cPanel acts as the user-facing interface. Successful exploitation of CVE-2026-41940 grants an attacker control over the cPanel host system, its configurations and databases, and websites it manages. A naive Shodan query for potential targets returns approximately 1.5 million cPanel instances exposed to the internet that may be vulnerable.
A managed cPanel host, KnownHost, stated that CVE-2026-41940 is actively being exploited in the wild, with speculation of targeted zero-day exploitation happening as early as February 23, 2026, prior to the vulnerability’s public disclosure. Security firm watchTowr has published a technical analysis and proof-of-concept exploit for CVE-2026-41940. As such, widespread exploitation in the wild is expected to be imminent.
Technical overview
Systems exposing the affected web service software are vulnerable by default.
As of April 29, 2026, a technical analysis and proof-of-concept exploit have been published by security firm watchTowr. CVE-2026-41940 is an authentication bypass caused by a Carriage Return Line Feed (CRLF) injection in the login and session loading processes of cPanel & WHM.
Before authentication occurs, `cpsrvd` (the cPanel service daemon) writes a new session file to the disk. The vulnerability allows an attacker to manipulate the `whostmgrsession` cookie by omitting an expected segment of the cookie value, avoiding the encryption process typically applied to an attacker-provided value. Attackers can inject raw `\r\n` characters via a malicious basic authorization header, and the system subsequently writes the session file without sanitizing the data. As a result, the attacker can insert arbitrary properties, such as `user=root`, into their session file. After triggering a reload of the session from the file, the attacker establishes administrator-level access for their token.
Mitigation guidance
Organizations running on-premise instances of cPanel & WHM or WP Squared should prioritize upgrading to a fixed version on an emergency basis. Some hosting providers have opted to temporarily institute workaround TCP port blocks for cPanel & WHM web services on ports 2083 and 2087. However, defenders are strongly advised to patch, rather than implement workarounds.
Affected Software:
cPanel & WHM 11.110.0 versions prior to fixed version 11.110.0.97
cPanel & WHM 11.118.0 versions prior to fixed version 11.118.0.63
cPanel & WHM 11.126.0 versions prior to fixed version 11.126.0.54
cPanel & WHM 11.132.0 versions prior to fixed version 11.132.0.29
cPanel & WHM 11.134.0 versions prior to fixed version 11.134.0.20
cPanel & WHM 11.136.0 versions prior to fixed version 11.136.0.5
WP Squared 11.136.1 versions prior to fixed version 11.136.1.7
Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-41940 with authenticated vulnerability checks expected to be available in the April 30, 2026 content release.
Generative AI brings promising innovation, transforming how individuals and organizations approach everything from customer service to content creation and more. As AI continues to expand its capabilities, organizations are increasingly focused on how they can integrate the responsible AI concepts into the development lifecycle of their AI applications.
Research from Accenture and Amazon Web Services (AWS) reveals compelling evidence for the business value of responsible AI practices, both internally within their organizations and externally to their users. Organizations that communicate a mature approach to responsible AI see an 82% improvement in employee trust in AI adoption, which directly leads to increased innovation. Additionally, companies that offer responsible AI-enabled products and services experience a 25% increase in customer loyalty and satisfaction.
Understanding the core dimensions of responsible AI
AWS identifies these key dimensions that form the backbone of responsible AI implementation:
Safety focuses on preventing harmful system output and misuse. This dimension focuses on steering AI systems to prioritize user and system safety.
Controllability focuses on mechanisms that monitor and steer AI system behavior. This dimension refers to the ability to manage, guide, and constrain AI systems to operate within specific parameters.
Fairness considers the impacts of AI on different groups of users.
Explainability focuses on understanding and evaluating system outputs.
Security and privacy focuses on making sure that data and models are appropriately obtained, used, and protected.
Veracity and robustness focuses on achieving correct system outputs, even with unexpected or adversarial inputs.
Governance makes sure that development, deployment, and management of AI systems align with ethical standards, legal requirements, and societal values.
Transparency focuses on understanding how AI systems make decisions, why the systems produce specific results, and what data the systems use.
When you implement AI systems, you should build safety into every phase of the AWS responsible AI lifecycle. The responsible AI lifecycle consists of the following three phases, each with distinct responsibility considerations for the safety dimension:
In the design and development phases, thoroughly evaluate potential safety risks. Understand what you want your AI application to do, what you don’t want it to do, and what you want to prevent it from doing. You should build safety guardrails into your systems from the beginning and make sure that your development teams understand the capabilities and limits of your AI application.
In the deployment phase, theory meets reality. During this phase, you should implement robust safety measures through multiple layers, from comprehensive user training to proactive monitoring and review processes. Every application, product, and feature must include clear safety protocols and user guidelines. You must think beyond the launch of an application and consider how to launch a holistic safety framework. This framework—which can contain steps such as red team testing—must protect your brand, users, and stakeholders.
Inthe operations phase, it’s important to maintain vigilance. Safety, like security, isn’t something you set up once and then ignore. Safety requires continuous monitoring and adaptation. To catch potential safety issues early, you can implement real-time feedback mechanisms to conduct regular performance evaluations. You can also continuously monitor for shifts in how your application is used, or functions that could compromise safety. Because safety considerations and risks evolve as technology evolves, it’s crucial to understand that adjustments are necessary over time.
Foundation models in Amazon Bedrock are inherently designed with safety mechanisms to prevent harmful outputs. However, you can implement additional input safety systems in production environments to provide critical early detection capabilities to identify problematic content, users, or patterns.
Note: Amazon Bedrock might implement automated abuse detection mechanisms to identify potential violations of the AWS Acceptable Use Policy (AUP) and Service Terms, including the Responsible AI Policy or a third-party model provider’s AUP.
To maintain trust in your AI services, preventative action is key, while also efficiently planning and managing development resources. Introduce observability and safety guardrails early in development to support long-term scalability and help identify potential issues before they affect your users. To begin this process, thoroughly scope your AI use case with the following actions:
Understand your users
Anticipate potential misuse scenarios
Define your risk tolerance
This scope guides your development of a precise safety framework that addresses the specific risks of your AI implementation while you maintain expected performance. For this scope, you can use AWS specialized tools designed specifically to monitor and protect Amazon Bedrock applications.
Using CloudWatch to monitor Amazon Bedrock
Amazon CloudWatch provides essential visibility into AI system behavior and performance. When you configure comprehensive logging, you can capture important information across user segments and interaction types, such as the following:
Request volumes
Response latencies
Rejection rates
Content filtering triggers
You can use this information to identify potential abuse patterns or unexpected behaviors before they affect operations. CloudWatch dashboards visualize metrics according to monitoring priorities, and automated alerts provide prompt notification when you exceed thresholds. This infrastructure transforms interaction data into actionable insights and supports continuous safety improvement.
Note: By default, Amazon Bedrock logging is turned off. You must turn on logging for your application. To configure this, contact your account manager.
Using Amazon Bedrock Guardrails to customize safeguards
Amazon Bedrock Guardrails offers configurable protection mechanisms tailored to specific risk profiles and content policies. You can customize Bedrock Guardrails to match your application requirements, such as:
Configure sensitive information detection and redaction parameters aligned with data policies
Additionally, you can configure controls that prioritize accuracy and prevent hallucinations while maintaining creative flexibility based on your application needs. When you thoughtfully configure Guardrails, you can balance performance and safety according to your specific use case requirements and risk factors.
The abuse response process
As AI safety evolves and new risks emerge, abuse might still occur even if you implement safety mechanisms. If you receive an abuse report from the AWS Trust & Safety team, then complete the following steps to help effectively address the issue:
Acknowledge receipt: Acknowledge the receipt of the abuse report within 24 hours. If your team is still conducting their investigation, then inform AWS that the investigation is ongoing. Provide the number of days expected to complete the investigation.
Investigate the issue: Thoroughly investigate the issue, including examining the logs (if enabled), reviewing Amazon Bedrock inputs, and checking for unauthorized access. While AWS abuse reports include a small sample of prompt IDs for you to investigate, investigate usage of your Amazon Bedrock application. Check for patterns to see if there’s a systemic issue that’s leading to abuse.
Take appropriate action: If appropriate, take action to implement fixes, update safeguards, address violating users, or redesign features. Consider if you need systemic or root-cause fixes, rather than addressing one abusive end user. An abuse incident by one user could indicate vulnerabilities in your safety mechanisms that can lead to continuous abuse.
Report back to AWS Trust & Safety: Following your investigation and implementation of fixes, provide an update to AWS Trust & Safety on your findings and remediation steps. Be transparent about what happened and how you addressed the issue. If you think that no violation occurred, then provide context on how you came to this conclusion. Include examples of the prompts and your business use case where possible.
Conclusion
To learn more about safety and responsible AI development, explore AWS resources, including the Responsible AI portal and machine learning best practices documentation. These resources provide additional tools and frameworks to build safe, effective AI systems that drive innovation and maintain safety standards.
The Python packaging world now has a formal
governance council, of the form described in PEP 772 (“Packaging
Council governance process”), which was approved
by the steering council on April 16. It has been over a year
since the PEP was first proposed in February 2025 and it has undergone
lengthy discussions in multiple postings to the Python discussion forum. The
packaging council will have “broad authority over packaging standards,
tools, and implementations“; it will consist of five members who will
be elected in a vote that is likely to come in June—after PyCon US 2026 is held mid-May.
[…] Based on the high severity of the defense-in-depth issues
shown in this report, our assessment is that there is effectively no
separation between root and the plasmalogin service user account.
At this time there is no bugfix available by upstream, but a
security fix is planned for the next Plasma release on May 12. We have
not been involved in upstream’s bugfix process so far and have no
knowledge about the approach that will be taken to address the issues
from this report.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.