Every time Cloudflare opens a new TLS 1.3 connection to an origin server, we have to make a guess: the protocol requires us to commit to a key agreement algorithm in the very first packet we send, before the origin has told us anything about itself or what it can support. If we guess right, the handshake completes in one round trip. Guess wrong, and the origin replies with a HelloRetryRequest, we start over, and the connection costs two round trips.
For years, our guess was the same for every origin on the Internet: X25519. Widely supported, but as it turns out, suboptimal for roughly 30% of the origin connections we've since measured.
Today we're announcing Automatic Key Exchange, an extension of Automatic SSL/TLS that replaces the guess with a measurement. We probe each origin to learn which key agreement algorithms it supports and prefers, then lead with that algorithm on the first try, preferring the post-quantum hybridX25519MLKEM768 wherever the origin can speak it.
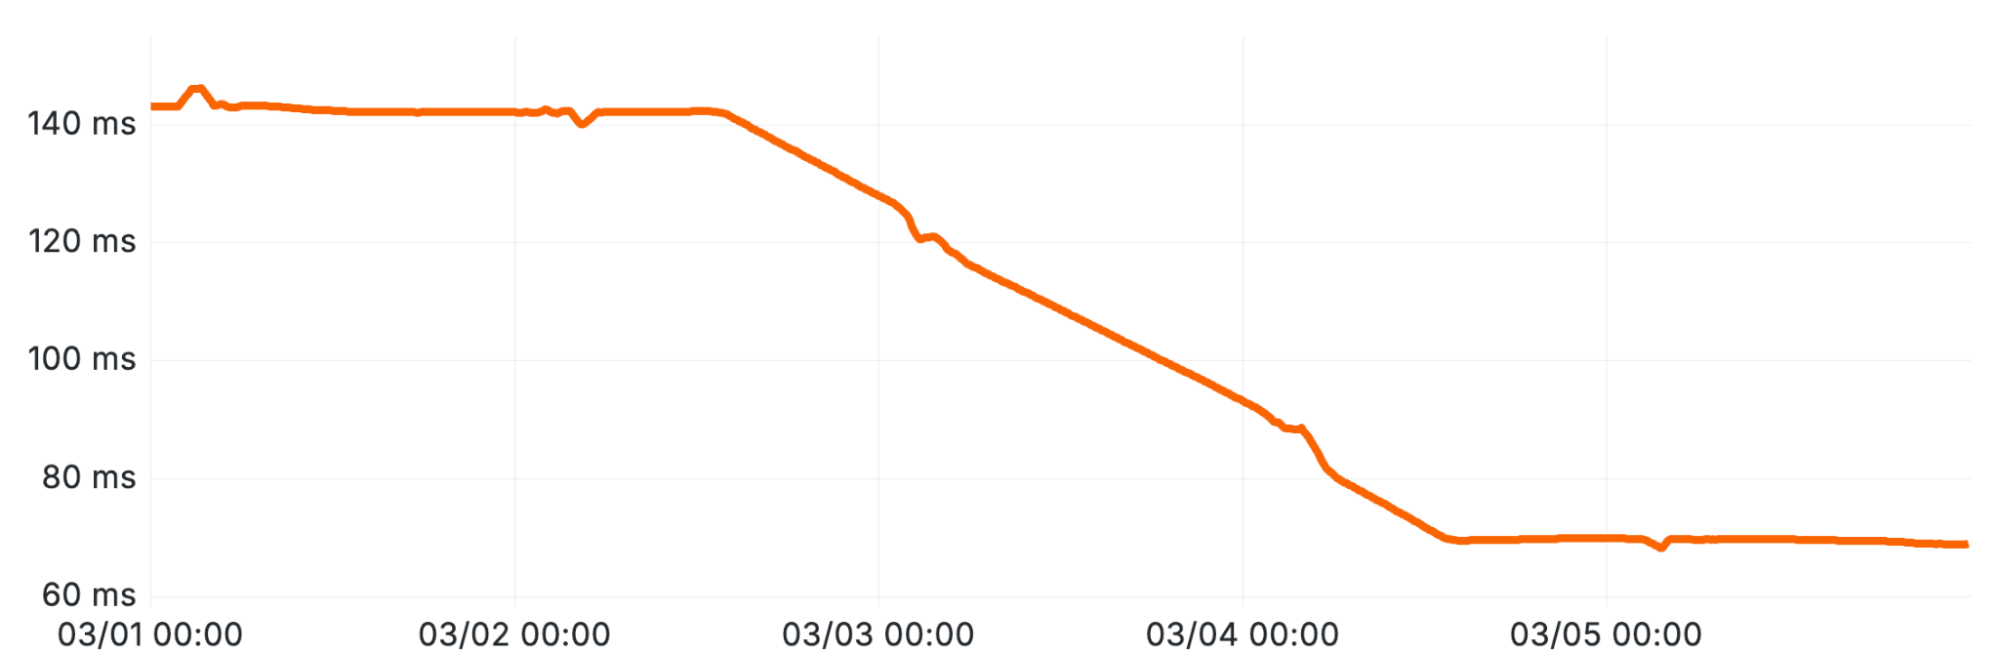
With the ongoing rollout of Automatic Key Exchange across origin connections, HelloRetryRequests fell from roughly 52% to 3.7%, cutting more than 150 ms off connection handshake latency at p90. In addition, as part of our ongoing rollout, hundreds of thousands of domains now have post-quantum origin connections that nobody had to configure, with that number growing daily.
While the milliseconds are important, that second part may matter more. Somewhere right now, an adversary is recording encrypted traffic it can't read yet, betting that it will be able to in the future (an attack known as harvest-now, decrypt-later). Cloudflare is sprinting to make the Internet quantum-secure by 2029, the year some industry experts estimate classical encryption algorithms could be breached. That day has a name: Q-Day. Meeting that deadline can't depend on millions of website operators each becoming expert cryptographers. It has to be automatic. Until today, preferring post-quantum connections required a manual setting: either you turn them on from Cloudflare’s side, or you have your origin server insist upon them. It was easy to get wrong. But today it’s just … automatic!
TLS 1.3 handshake: guessing the key exchange algorithm
Every secure web connection starts with a TLS handshake, which authenticates the server and derives a shared secret key. Our previous Automatic SSL/TLS blog posts cover that process in detail.
As Cloudflare operates as a reverse proxy, what appears to be a single secure connection is actually two: one between the visitor and Cloudflare, and a second between Cloudflare and the origin server. Each connection operates independently, with its own handshake, identity checks, and encryption keys.
Automatic Key Exchange affects the second connection. When Cloudflare connects to the origin, Cloudflare acts as the TLS client and must begin the handshake. We initiate the connection by sending a ClientHello message containing the hostname and a list of supported key agreement algorithms.
In the happy path, TLS 1.3 can establish a new encrypted connection in just one network round trip (shown on the left in the diagram above). In this case, Cloudflare sends a ClientHello listing its supported key agreement algorithms, along with one or more client keyshares. If the origin accepts that choice, it responds and the handshake completes. This predictive key exchange is an innovation of TLS 1.3, and a large part of why it’s faster than TLS 1.2.
Otherwise, if the origin prefers a different option, it sends a HelloRetryRequest (HRR) and asks Cloudflare to try again (the flow on the right in the diagram above). Cloudflare then sends a second ClientHello, generating a new client keyshare based on the key agreement algorithm specified by the origin. The connection still succeeds, but the retry adds a full network round trip before Cloudflare can fetch content. This is like missing a shortcut in Mario Kart: you still reach the finish line, but you lose the time the shortcut was supposed to save.
Either way, using the client keyshare,the server generates the shared key. The server then returns a server keyshare with which the client can also compute the shared key. This shared key is used to protect the rest of the connection using symmetric cryptography, such as AES.
The cost of the safe guess
For years, our initial client keyshare guess for origin connections using TLS 1.3 was static; we'd always send X25519 while advertising support for other key agreement algorithms. This was a safe strategy because over 95% of origins support X25519, and any origins that didn’t could issue a HelloRetryRequest (HRR) without breaking the connection.
However, X25519 is vulnerable to quantum computers. Since September 2023, we have advertised support of post-quantum key agreement to origins: first as X25519Kyber768Draft00 and today as X25519MLKEM768 (the standardized version of the algorithm). Crucially, advertising support differs from leading with a keyshare in the ClientHello. An X25519MLKEM768 keyshare is 1,216 bytes compared to X25519's 32 bytes, pushing the ClientHello past a single network packet. While the TLS standard allows multi-packet segments, some legacy middleboxes and origin servers can fail when receiving ClientHello messages split across multiple packets. In our previous study, around 0.34% of scanned origins failed to complete the TLS handshake when receiving a post-quantum keyshare first, while the vast majority of origins still relied on classical X25519.
Therefore, to prevent any possible breakage of origin connections, we used HRR as a safety valve. We only advertised post-quantum support, sent a classical X25519 keyshare, and required capable origins to request a post-quantum exchange via retry. For origins that did not support the HRR flow, customers had the option to manually opt into leading with X25519MLKEM768 keyshare. Between 2023 and today, the percentage of origins supporting post-quantum key exchange algorithms grew from 0.5% to 12.8%, and we expect that to keep climbing as hosting stacks upgrade to PQ safe algorithms.
While safe, this default of only upgrading to post-quantum secure connections via retry added unnecessary latency for two reasons:
While all modern builds of OpenSSL, BoringSSL, and rustls support X25519MLKEM768, they handle a classical X25519 keyshare differently. Depending on the build, some older builds may accept it by default unless explicitly configured to prioritize the post-quantum secure keyshares, while newer builds will immediately issue an HRR to prioritize post-quantum connections.
Over 6% of origins prefer either P-256 or P-384 over X25519, triggering an HRR round trip even for purely classical connections due to our static choice of initial client keyshare.
To eliminate these wasted round trips, we began scanning origin servers to map their exact key agreement capabilities as part of Automatic SSL/TLS. Using these scan results, we automatically tailor our initial keyshare on a per-origin basis: maximizing post-quantum connections without risking site outages, all while making our connections faster for applicable domains.
Extending Automatic SSL/TLS to the post-quantum age
Automatic SSL/TLS now includes Automatic Key Exchange. Across millions of origins, guessing different keyshares carries operational risk, because we have no advance knowledge of how any individual origin is configured. So rather than infer capability, we measure it directly, reusing the scanning pipeline that already powers Automatic SSL/TLS.
For a growing number of origins, this delivers post-quantum key agreement on the very first try at connection setup, without extra round trips and without requiring any manual setup.
This is how it works:
For each TLS 1.3 capable origin, we run a series of a few lightweight TLS handshakes, each offering exactly one key agreement group: X25519, P-256, P-384, P-521, or X25519MLKEM768. Together these probes tell us the full set of algorithms the origin supports. And because the active scanning happens outside your production traffic path, we confirm that both your origin and the network in between can handle connections with a stronger key agreement before any real traffic depends on it.
A single domain often fronts multiple subdomains that may resolve to different origins with varying capabilities. We evaluate each subdomain independently and weight the results by its actual traffic volume. This ensures a domain-wide preference reflects HTTP traffic volume rather than weighing a dormant subdomain equally with your busiest endpoint. For example, if almost all traffic hits your www and api subdomains, those endpoints would heavily determine the key exchange preference for the entire domain.
From the key agreement groups an origin supports, we then select the strongest candidate using a strict priority order: post-quantum hybrids (X25519MLKEM768) first, falling back to the fastest classical algorithm accepted by the origin (X25519, P-256, P-384, or P-521).
Once we know the optimal key-agreement an origin prefers, we start rolling it out. The new preference goes to a small share of that origin's traffic first, and the system monitors its failure and HelloRetryRequest (HRR) rate while it runs. If retries climb above that origin's baseline, we roll the change back, the same way Automatic SSL/TLS reverts an encryption mode upgrade that may misbehave. At the worst case of rolling back, a bad key-agreement preference costs us an additional round trip latency, not a broken TLS connection for the duration of the rollout phase.
Origin configurations change over time: a customer moves to a new load balancer, a TLS library ships post-quantum support in a routine release, an operator turns off an older key-agreement algorithm support. We rescan every origin daily, so a server that adds post-quantum support, or stops supporting the curve we were using, gets a new preference at the next scan.
For most customers, there is nothing to configure. If your origin speaks TLS 1.3, we will automatically negotiate the strongest key exchange it supports, for instance, if an origin supports X25519MLKEM768, Cloudflare prefers it and can establish post-quantum key agreement without any extra round trip latency.
Configuring Automatic Key Exchange
Automatic Key Exchange is active by default for all existing and new domains, requiring no manual action for most setups. If you want, you can manage these settings independently in the Cloudflare dashboard under SSL/TLS > Overview > Configure > Origin connection & post-quantum encryption.
With the Automatic Key Exchange toggle enabled, Cloudflare scans your origins out-of-band and leads with a dynamically selected keyshare. With it disabled, scanning stops and Cloudflare reverts to a fixed/static default key agreement order.
We have also introduced a new Compliance requirements setting under Automatic Key Exchange. You can filter which key agreements Cloudflare is permitted to use and advertise support for origin connections. When configured, Automatic Key Exchange and all origin-facing traffic strictly observe these rules:
Post-quantum hybrid: Restricts negotiation exclusively to hybrid post-quantum key agreements (X25519MLKEM768), removing classical algorithms entirely. All your successful origin TLS 1.3 connections will be guaranteed to be post-quantum secure.
Selecting both options requires an algorithm that satisfies both criteria simultaneously; if no overlapping key agreement exists, the configuration is rejected. See the Automatic Key Exchange documentation for details.
By selecting these options, you configure your intent rather than specific algorithms. This ensures that as compliance standards evolve or new post-quantum algorithms emerge, your configuration stays up to date automatically.
However, these requirements are worth approaching carefully. They do not grant an origin new cryptographic capabilities, they only narrow what Cloudflare can negotiate.
An important note: Enforcing post-quantum hybrid on an origin that lacks X25519MLKEM768 support leaves no mutually supported algorithm, causing all TLS 1.3 connections to fail. Unless you have a strict policy obligation to enforce post-quantum exchange or FIPS compliance across every connection, leave both options unselected and allow Automatic Key Exchange to negotiate the optimal algorithms safely for you.
Making the Internet safer and faster, together
Automatic Key Exchange works for domains whose origins speak TLS 1.3 (as predicting preferred key agreement method is a TLS 1.3-only feature). It’s enabled by default, and our scanning pipeline has already assigned key exchange preferences to well over a million domains while enrollment continues across the remaining network.
From that initial cohort, we found that roughly 64% of them stayed on the classical X25519 as their preference, so nothing about their connections changed. Around 33% of them now have their preference set to X25519MLKEM768, which causes traffic to those origins protected from harvest-now, decrypt-later quantum attacks in a single round trip. The remaining 3% selected a different classical curve preferred by their origin, such as P-384, P-256, or P-521.
Approximately 9,000 domains each day have their key agreement preference set to a key agreement method other than X25519. Nearly all of these move directly to preferring post-quantum key exchange, while the remainder adopt other classical curves better supported by their origin’s TLS configuration.
As we mentioned earlier, prior to Automatic Key Exchange, almost every post-quantum origin handshake required a HelloRetryRequest (HRR) because our static initial guess defaulted to classical X25519. The result was that post-quantum connections paid a mandatory second round trip before completing the TLS handshake.
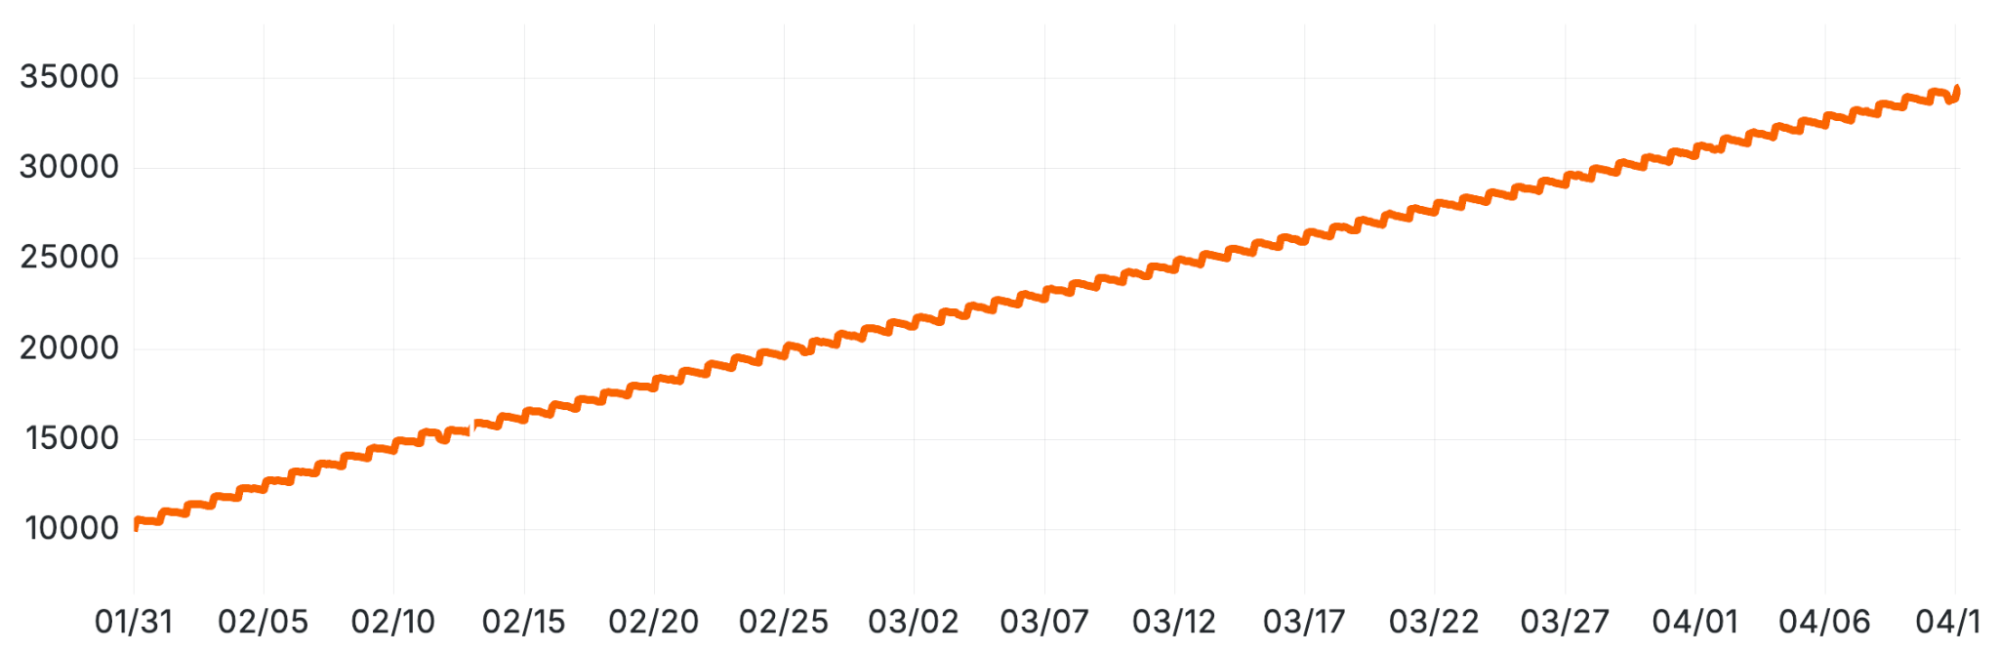
With the rollout underway, that latency penalty is virtually gone for almost all post-quantum capable origins: 99.2% of post-quantum TLS 1.3 connections of the currently scanned cohort of origins now complete in a single round trip. Beyond removing the extra round trip, we see that across that cohort, post-quantum origin traffic keeps growing from roughly 25 billion connections to 45 billion per day. A significant part of that growth has come from Automatic Key Exchange upgrading classical connections to a post-quantum preference for scanned origins.
Many origins support multiple key agreement algorithms without preferring one over another. For example, an origin that supports post-quantum key agreement may still accept a classical (X25519) key share without rejecting it or issuing an HRR. Passive observation, therefore, cannot reveal the origin’s full capabilities. Active probing allowed Automatic Key Exchange to uncover thousands of origins whose post-quantum support never appeared in their origin traffic.
Once our scanner discovered such origins, and updated their client keyshare preference, post-quantum connections quickly accounted for the vast majority of traffic to these origins. Other classical key agreement algorithms represent a much smaller share for these upgraded domains, primarily driven by multi-origin setups with a mix of post-quantum and classical-only backends. Automatic Key Exchange does more than just drive post-quantum adoption. It also helps pair origins with their preferred classical curve (other than X25519), reducing overall HRR rates across all scanned origins.
Before we enabled Automatic Key Exchange, roughly 52% of origin connections for the scanned domains required an HRR. That rate fell to just 3.7%. Avoiding an HRR removes an entire round trip from TLS connection setup, reducing p90 latency more than 150 ms for the scanned origins. This particularly benefits dynamic requests and CDN cache misses that may require a new TLS 1.3 connection to the origin, ultimately reducing latency for eyeballs. Requests sent over existing keep-alive connections do not require a new handshake and are therefore unaffected.
Is the server post-quantum capable?
There are a number of different tools to use to find out if a server supports post-quantum key agreement. We offer one of these tools via Cloudflare Radar. Enter the hostname or IP addresses of your server, and we will check if it supports post-quantum TLS key exchange. Note that if you enter a hostname proxied by Cloudflare, Radar will check the connection to Cloudflare rather than your origin server behind it.
Beyond verifying algorithm support, we have added the ability in the tool to check forpost-quantum TLS implementation bugs. If the results come back negative, it will also try to characterize the reason for the failure. Failures often stem from legacy middleboxes, firewalls, or server buffers dropping multi-packet payloads or failing to reassemble a ClientHello split across TCP segments. Other times the origin gives up on an unrecognized key share instead of sending a HelloRetryRequest as TLS 1.3 requires, or sends one and then cannot finish the handshake.
Radar gives you a clear picture of whether the network path handles post-quantum traffic cleanly. Automatic Key Exchange will not switch a domain whose origin fails these checks, so clearing them is what lets the upgrade happen.
What if your origin doesn't support post-quantum key agreement yet?
Even if your origin does not yet support post-quantum encryption today, the good news is that enabling Auto Key Exchange will still be beneficial. Automatic Key Exchange finds what your origin supports. If X25519MLKEM768 is unavailable, Cloudflare continues using a compatible classical key agreement and can still avoid unnecessary HelloRetryRequest round trips by learning which one your origin prefers.
However, Automatic Key Exchange can only prefer post-quantum connections when your origin server already supports the key agreement algorithm. Today, we see over 12% of individual origins across our network support post-quantum encryption. Post-quantum secure algorithms support in TLS server implementations is increasing as recent versions of BoringSSL, OpenSSL, and rustls include support. The enterprise origin stacks, cloud load balancers, and embedded TLS terminators are upgrading on their own timelines.
If you want to add post-quantum protection capability for your domain’s origin-facing connections, you have two options:
You can use Cloudflare Tunnel. The connection between cloudflared and Cloudflare already uses post-quantum key agreement. This is the simplest option when you cannot change the TLS software on your public origin endpoint.
You can upgrade your TLS endpoint. Many current frameworks and TLS libraries enable X25519MLKEM768 by default. However, if you previously configured allowed curves manually for your server’s TLS configuration, those legacy settings might override the new defaults. It is important to audit every device terminating or inspecting TLS—including load balancers, WAF appliances, and other middleboxes—to ensure X25519MLKEM768 is enabled on everything that sits between your origin and Cloudflare. If you’re on a managed hosting service, ask your provider whether it supports X25519MLKEM768 (many do).
We’ve been building Automatic SSL/TLS in public since 2024. Automatic Key Exchange is the second step in a longer arc, not the last. We’ve been public about what’s on the roadmap since then and will continue to provide updates as we ship. A few specific things we’re working on:
Per-origin preference granularity
Today, Automatic SSL/TLS makes its decisions at the domain level. One origin server's behavior can hold the whole domain back. We're working on a per-subdomain/per origin granularity so that key agreement (and SSL/TLS encryption modes) can vary across the multiple origins that serve a single domain.
On-demand scans
If you've just upgraded your origin's TLS stack, you shouldn't have to wait for the next scheduled scan by Automatic SSL/TLS. Originally, we wanted to scan enough to keep up with changes on the origin, but not too much so as to burden origins who ultimately return the same security information. We're building an option to trigger an on-demand rescan from the dashboard or API, so post origin upgrade you can move to the better key agreement immediately rather than waiting for our system to catch up.
Beyond triggering instant updates, this on-demand scan will live directly in your Cloudflare dashboard as a diagnostic tool. It will let you test your own origin server's behavior on demand and see exactly which key agreements it can successfully negotiate, and characterize the reasons for any failures (similar to the external Cloudflare Radar scanning tool).
Automatic post-quantum origin authentication
Post-quantum key agreement keeps today's traffic from being decrypted by a future quantum computer. It does nothing about an attacker who uses one to forge a certificate and impersonate your origin. Closing that gap takes post-quantum authentication, which came to origin connections earlier this year when Authenticated Origin Pulls and Custom Origin Trust Store gained support for ML-DSA certificates.
There is an important issue to deal with here: downgrades. Imagine your origin server supports both a classical RSA/ECDSA certificate and a new post-quantum ML-DSA certificate so legacy clients don't break. On Q-Day, an active adversary sitting between Cloudflare and your origin could intercept the TLS handshake and silently drop the post-quantum offer. Cloudflare, seeing only a classical response, would fall back to validating the legacy RSA/ECDSA certificate, which the attacker can forge using a quantum computer.
Preventing this downgrade in the broader WebPKI is complicated. One proposed path involves Certificate Authorities (CAs) placing a post-quantum signature on a classical certificate to prove that a legacy server truly doesn't support PQ yet. While this is a likely direction for the public web, it will take some time and coordination. What’s quicker (if possible!) is to stop trusting classical certificates altogether.
And for origin connections, we can! We plan to extend Automatic SSL/TLS scanning to detect origin support for post-quantum authentication (ML-DSA certificates; and in future Merkle Tree Certificates). Once our scanner identifies such an origin, Cloudflare can automatically disable classical fallback for customers who want strict post-quantum protection, eliminating downgrade risks without disrupting un-upgraded endpoints.
Check it out
At Cloudflare, we believe that strong security on the Internet should be free, automatic, and on by default. Universal SSL made encryption-by-default real for the browser-to-Cloudflare connection. Automatic SSL/TLS is doing the same for the Cloudflare-to-origin connections, and now extends that work to post-quantum key agreement.
If you want to see what your origin encryption level looks like today, check the SSL/TLS section of your dashboard. If you want to verify your origin's post-quantum readiness directly, Cloudflare Radar will tell you if you need to update your server stacks. And if your origin already supports post-quantum, Automatic Key Exchange will tell Cloudflare so that we will connect to your origin faster and more securely.
Memory costs are increasing dramatically. Both RAM and hard disk drive prices have exploded over the past year. At Cloudflare, we run several massively distributed storage products (including our famous CDN) that rely on making efficient use of the memory we have deployed so we can continue to serve all of our customers.
With this in mind, we prototyped a way to expand effective cache capacity. By encoding eligible assets with Zstandard inside Pingora, the architecture trades a minor CPU increase for significant storage and cross-data center bandwidth savings.
We have been prototyping a system called Cache Transcoding, which I built during my internship at Cloudflare as part of the 1.1.1.1 Intern Program. When an eligible response enters the cache, we encode it using Zstandard, or zstd, before writing it to disk. We keep that compressed form while the asset lives in the cache and moves between data centers via Tiered Cache, then decode it before serving the response to the client.
In our initial testing, this encoding shrunk eligible assets to ⅓ of their original on-disk size on average. The estimated extra CPU cost in our origin-facing proxy was small, but that is the trade. A small increase in CPU gives Cloudflare petabytes of effective cache capacity and reduces the data transferred between our data centers. The encoding cost is paid once when an asset enters the cache. The storage and bandwidth savings continue every single time that asset is reused.
What is Zstandard?
Zstandard, or zstd, is a lossless compression algorithm developed by Yann Collet at Facebook and open sourced in 2016. Lossless means that after compressed data is decoded, every byte is identical to the original. We can change how an asset is represented on disk without changing the asset itself.
Zstd is designed to balance compression ratio with speed. In our earlier browser compression testing, it compressed data 42% faster than Brotli while producing nearly the same file size, and produced files 11.3% smaller than gzip at a comparable speed. That balance matters because Cache Transcoding would touch a large amount of traffic, so both encoding and decoding need to stay fast.
The prototype uses zstd level 3, giving us most of the compression benefit without turning cache fills into a CPU bottleneck.
Cloudflare traditionally stores an asset using the content encoding supplied by its origin. If an origin sends an uncompressed response, we store those uncompressed bytes on disk and transfer them between data centers in the same form. Cache Transcoding adds compression inside the cache itself.
Not everything is worth compressing
Transcoding does not mean compressing everything. Images, video, and fonts are usually compressed already. In our traffic sample, this media slice represented 21.4% of requests but 63.3% of bytes. Compressing it again would burn CPU for nothing.
Compressible text is different. HTML, JSON, CSS, and JavaScript represented 67.3% of requests and 22.3% of bytes. Within that text slice, approximately 71% arrived uncompressed with Content-Encoding unset and it compresses well.
In our controlled test corpus, the eligible assets compressed by roughly 2.8 times.
Encoding is more expensive per byte, but assets are served far more often than they are filled.
By changing how assets are represented, existing hardware could store more customer content.
Fewer bytes on disk mean each server can retain more objects. This increases cache density and reduces the likelihood that useful content is evicted because an uncompressed representation consumed more space than necessary.
The smaller representation also helps as an asset moves through Tiered Cache because it reduces the data transferred between Cloudflare data centers, making backbone usage more efficient.
Paying the compression cost once
Compression is never free. Encoding and decoding both use CPU, so the important question is whether the byte savings are worth the processing cost.
At zstd level 3 (often the default balance of speed and compression size output), our model kept the extra CPU cost to a few percent under the traffic and reuse assumptions we tested.
We initially considered limiting transcoding to popular content, since hot assets are reused more, but it did not help. Decoding happens every time an asset is served, so limiting the feature to only the hottest content reduced the storage saving without cutting CPU by the same amount.
The simpler policy performed better. Transcoding all eligible compressible text at or above 4 kibibytes (KiB) captured nearly all of the measured storage benefit, while remaining within the CPU budget.
How Cache Transcoding works
On a cache miss, our Pingora-based proxy encodes the body using zstd before writing it to disk. The cache metadata records that the stored representation is compressed and preserves the original content length. Before the response leaves the proxy, the body is decoded back to its original identity representation.
On a cache hit, the stored zstd object is read from disk and decoded. With Tiered Cache, the compressed representation is transferred from the upper tier to the lower tier in the compressed form. Decoding only happens on the client-facing hop.
On a full cache miss, the upper tier fetches identity bytes from the origin. Those bytes are encoded once, stored as zstd, and transferred to the lower tier in their compressed form. The lower tier also stores the zstd representation, then decodes it for the request path.
If the lower tier misses but the upper tier already has the object, the origin is not involved. The compressed object moves directly between the cache tiers. It remains compressed on the wire and on disk, then is decoded once at the lower tier.
If the lower tier already has the object, no network transfer or encoding is needed. The lower tier reads the zstd bytes from disk, decodes them, and passes the original asset onward.
The storage encoding marker prevents an object from being encoded more than once. A cache layer receiving an object from another tier can see that it is already stored using zstd, and preserve it in that form.
Why we only transcode certain text
The fastest compression operation is the one we do not need to perform. Cache Transcoding therefore uses a series of eligibility checks to avoid content that is unlikely to benefit.
The prototype only transcodes a 200 OK response when Content-Encoding is unset, the Content-Type is compressible text, and the response has a known Content-Length of at least 4 KiB. Slice subrequests, responses using active upstream compression, range requests, precompressed responses, unknown length bodies, and binary content remain unchanged.
The 4 KiB threshold removed a large number of tiny requests while leaving out only about 1% of the otherwise eligible bytes. Lowering it would add per-object overhead without saving much more storage.
The threshold and zstd level are both parameters rather than permanent limits. We started with zstd level 3 and a 4 KiB minimum because they gave us a conservative way to measure the architecture. With the initial CPU budget understood, we can test whether higher compression levels improve the ratio enough to justify their additional cost.
Testing over one million requests through the cache
We exercised the prototype against a controlled test zone and correlated each request across request logs, Prometheus metrics, and Jaeger traces.
The correctness campaign covered cache misses, cache hits, single-hop fills, Tiered Cache fills, and more. We varied cache keys to make each request follow a specific path and used traces to confirm where encoding and decoding occurred.
One performance campaign sent more than a million requests across 10 cache servers. Half of the campaign ran with Tiered Cache disabled and the other half with it enabled. This allowed us to measure local cache behavior separately from transfers between cache tiers.
The two assets were approximately 195 KiB and 272 KiB, and both compressed by roughly 2.8 times. This was deliberately a compressible test corpus. It gave us a clear signal for validating the architecture, but it does not represent every text object on the Internet. A broader corpus is required before treating the measured compression ratio as a fleet-wide constant.
Compress once, benefit many times
What this experiment showed us is that there are significant efficiencies we can still deploy across our caching service that can benefit all of our customers. What we built for Cache Transcoding shows that the trade is favorable under the conditions we tested. The architecture preserved the content and remained within the CPU budget.
For next steps, we plan to evaluate higher zstd levels, test a broader range of content types and object sizes, tune different parameters from the eligibility criteria and more. Future work can also examine range requests, pre-compressed origin responses, and passing the compressed object directly to downstream components that already support it without decoding.
Throughout my internship, I’ve had the wonderful opportunity to work alongside Cloudflare's engineering teams on the real infrastructure that stores and serves content across our global network. If you want to start your career by helping build a better Internet, explore our internship opportunities and job openings.
Big Pineapple, the platform behind 1.1.1.1, Gateway DNS, DNS Firewall, AS112, and several other Cloudflare DNS services, stores over 250 billion DNS cache entries at any given time. At that scale, wasting a single byte per entry costs more than 250 gigabytes of memory across our fleet.
Five successive changes to how cache entries are stored in memory cut the per-entry footprint by over 50%. Across our fleet, these changes freed up roughly 100 terabytes of memory, equivalent to the amount of RAM in 130 of our Gen 13 servers. The cache also got faster. Insert throughput rose 43% and lookup latency dropped 19%, as fewer allocations and better memory locality meant we did not trade speed for space.
What we cache
On cold start, Big Pineapple starts out with an empty cache. As DNS queries arrive, the cache fills until it hits its maximum entry count, at which point we evict older or less popular items to make room.
The exact cache size varies by data center. When EDNS Client Subnet (ECS) is in use, authoritative servers return different answers depending on the client's network, so we cache multiple versions of the same query. This increases both the number of entries and the memory each one consumes, making the optimizations in this post especially impactful for ECS-heavy locations.
Each item in the cache is a key-value pair. The key identifies what was queried:
The value stores the DNS response itself: the answer, authority, and additional record sections, along with metadata like the creation time, a hit counter, and the Time-to-Live (TTL).
Both structs have room for improvement. Several fields use types that carry overhead we don't need once the entry is stored.
Benchmarking memory usage
To measure the impact of each change, we benchmark by filling the cache with randomly generated entries that roughly match the traffic distribution we see in production: 56% A records, 25% AAAA, and 19% TXT. Each entry contains between one and four records.
TXT records serve as a stand-in for all non-A/AAAA record types in the benchmark. Their size is randomized between 64 and 224 bytes, close to the average response size we see for variable-length record types.
We track memory usage using a custom allocator that wraps Rust’s System allocator and records the number and size of allocations per cache entry. Alongside memory, we measure insert throughput and lookup latency across the full cache flow to make sure memory savings don’t come at the cost of performance.
These inputs approximate production rather than reproduce it exactly. Process memory also depends on traffic mix, cache occupancy, allocator state, and memory used outside the cache. We therefore measured resident memory across production instances during the rollout.
The cost of capacity
Vec<T> stores three fields: a pointer to heap-allocated data, the current length, and the total capacity. When you push an item, Vec checks whether the length exceeds the capacity and reallocates if needed. If there’s room, it just appends the item and increments the length.
Once we store a DNS response in the cache, however, we never modify it again. The capacity field serves no purpose, but still costs 8 bytes per Vec. The over-allocated heap space is wasted as well, as a Vec with capacity for eight items but only five stored leaves three slots unused on the heap.
Using Box<[T]> solves both problems. It can’t grow after creation, so it doesn’t need a capacity field or reserve space for future elements. The same applies to String, which also carries a capacity field. Box<str> drops it.
Each cache entry stores 8 Vec and String fields. Replacing them with Box<[T]> and Box<str> saves 8 bytes per field, 64 bytes per entry. It also eliminates the excess heap memory that Vec reserves for future growth. The combined savings add up to over 15 terabytes with over 250 billion cache entries.
Fewer lists, fewer pointers
Rather than storing the answer, authority, and additional sections in separate lists, we can store a single list with offsets to the start of each section. Since DNS record counts per section fit in a u16, we can use a u16 (2 bytes) for each offset, compared to the 8-byte pointer and 8-byte length that each separate Box<[T]> requires.
This removes two lists, each with an 8-byte pointer and 8-byte length, and replaces them with two 2-byte offsets, saving 28 bytes per entry.
These savings do not always map directly to the number of bytes removed from individual fields. Rust inserts padding to satisfy alignment requirements and rounds a struct’s size up to a multiple of its alignment. Removing a small field can therefore eliminate additional padding. For example, we also packed several boolean fields into a single bitflag. This reduced the surrounding padding, causing the struct to shrink by more than the size of the individual booleans.
Dropping the owner
Each DNS record has an owner, the domain the record belongs to. In many cases, this owner is identical to the domain being queried. For example, a query for example.com A returns two records with the same owner:
But when a CNAME is involved, for example, the record owner can differ from the queried domain:
The DNS wire format handles repeated owners using name compression, as defined in RFC 1035. Rather than encoding the same domain twice, subsequent occurrences store a 2-byte pointer to the first occurrence. A domain like www.example.com can encode just www followed by a pointer to where example.com already appeared in the message.
This works well on the wire, but in our cache we store the full owner name alongside each record. Following compression pointers during cache lookups is expensive on the hot path, so we trade memory for speed.
Most records, however, have an owner identical to the queried domain. For those, we can drop the owner entirely and infer it at read time. When the owner differs, such as the A records behind a CNAME, we store the full name.
When owner is None, response construction restores the queried domain from the cache key, avoiding a heap allocation. This means the record is no longer self-contained, but the cache key is already available during every lookup. When the owner differs, Some stores a pointer to the full name on the heap.
In practice, most cached records have an owner identical to the queried domain, so the majority require no heap allocation for the owner field.
Enum sizing
Rust enums are sum types: each variant can carry different data, but the enum is always the size of its largest variant.
Option is either Some and holds a value, or None and holds nothing. Both variants take the same amount of memory. The enum stores a tag indicating the active variant, followed by space large enough for the largest variant’s data. When the variant is None, that space is unused.
For record data, it seems natural to store each DNS record type as an enum variant:
But the enum is always as large as its largest variant. In our case, that’s NAPTR at 136 bytes. It stores three variable-length text fields, a domain name, and two integers. As a result, the full enum, including the variant tag and padding, becomes 144 bytes.
An A record only needs 4 bytes, and an AAAA record needs 16 bytes. A and AAAA make up over 80% of our traffic, so most records waste over 120 bytes on padding. Since a single cache entry can store many records this quickly adds up.
Boxing the variants
To solve this problem, we can box the larger variants of the enum, moving them to a separate heap allocation. The enum then stores an 8-byte pointer to the heap, where the data takes up only the size it actually requires.
For A and AAAA records, this saves 120 bytes per record. Smaller variant types like TXT and CNAME also benefit. They still occupy the 24-byte enum, but their heap allocation is sized to their actual data rather than padded to 144 bytes. NAPTR, the largest variant, actually pays slightly more. It now adds the cost of a heap pointer and allocation overhead. But NAPTR records are rare in practice, so the tradeoff is worth it.
But boxing the larger record variants introduces costs of its own.
The costs of boxing
Boxing has two costs. The first is allocator overhead. Each boxed variant becomes a separate heap allocation, and allocators round up to the nearest size class. Big Pineapple uses jemalloc, an allocator designed for multithreaded, allocation-heavy workloads. jemalloc groups allocations of similar sizes into fixed-size bins. A TXT record requests 32 bytes and fits exactly into a 32-byte bin, wasting nothing, but an MX record requests 40 bytes and rounds up to 48, wasting 8 bytes.
The second cost is poor memory locality. Without boxing, the record enum values for a cache entry sit in a single contiguous allocation. With boxing, data for each boxed variant lives in a separate heap region. Reading it requires following a pointer, and when that pointer lands far from the rest of the entry, the CPU has to fetch a new cache line. With millions of cache entries, boxed data ends up scattered across the heap rather than packed together.
Neither cost is catastrophic on its own, but eliminating both, as the next section shows, yields a measurable improvement in both memory usage and lookup latency.
Storing records in wire format
An obvious next step would be to store the full DNS response in wire format, patching only per-client fields like the message ID on each lookup. But this has drawbacks. DNSSEC records are only included when the client sets the DO (DNSSEC OK) flag. Storing a complete wire format message means either caching two variants, one with DNSSEC and one without, or filtering them out of an already-built message. There is also a cost to parsing the full message on every lookup, which the enum approach we just described avoids by storing already-parsed records.
As a middle ground, we store just the record data as raw bytes, while keeping the rest of the cache entry as structured fields. Instead of a list of parsed enum variants, we store the records as a single Box<[u8]> containing each record encoded as a 2-byte length prefix followed by its raw bytes.
This eliminates the per-variant enum overhead and the boxed heap allocations from the previous optimization. The data also becomes packed contiguously, which improves CPU cache locality. The tradeoff is that records can no longer be randomly indexed. We have to iterate through the buffer sequentially. This adds some complexity for features like round-robin rotation of A/AAAA records, but since record counts per entry are small, the cost is negligible.
When building a DNS response from cached records, most record types can be copied directly from the buffer into the outgoing message. Previously, each parsed record had to be serialized field by field back into DNS wire format. The new layout skips that work for A, AAAA, TXT, and all DNSSEC record types by copying their encoded bytes directly. Only records containing domain names, such as CNAME, NS, MX, and SOA, still require parsing so we can apply DNS name compression. Since records that support direct copying make up the vast majority of our traffic, this change reduces work on the lookup path. Combined with improved memory locality, this reduced cache lookup latency by 5% in our benchmarks.
To build the record data buffer, we write into a reusable scratchspace buffer that persists across cache insertions. Since previous writes have already grown it, the buffer rarely needs to be reallocated. Records vary in size, so we do not know the exact buffer size until they have been serialized. Once the records are in the scratchspace buffer, we allocate a Box<[u8]> and memcpy the data into it. This replaces the separate allocation for each boxed record with one allocation for all record data. It also avoids the waste from shrinking a Vec<u8>, where the allocator may not be able to reclaim the unused tail of the original allocation. In our benchmark, this change alone increased cache insert throughput by 13%.
The results
The production measurements show how the benchmarked per-entry savings translated to whole-process resident memory. The graph below shows p90, p98, and p99 memory usage across Big Pineapple instances. The first dashed line marks the start of the rollout on May 18, 2026, and the second marks its completion across all services on July 6, 2026. Each release introduced one or more of the optimizations described above, so memory usage dropped in steps rather than all at once.
As each release rolled out, restarted instances began with empty caches and consumed more memory as those caches filled. The stable plateaus therefore represent steady-state memory usage better than the initial dips.
Per-instance memory usage dropped across all percentiles. At p99, memory dropped from 9.3 GB to 5.3 GB, a 43% reduction in resident memory. At p90, memory dropped from 6.5 GB to 3.8 GB, a 42% reduction. Instances with fuller caches saw the largest absolute savings.
In our benchmarks, these five optimizations reduced the per-entry memory footprint from 953 bytes to 420 bytes, a 56% reduction. Per-entry allocations dropped from 1.1 KB to 461 bytes. The reductions measured in production are smaller because resident memory includes the cache alongside all other process data. After the rollouts settled, aggregate working-set memory across the fleet was roughly 100 terabytes lower.
Performance also improved. Cache insert throughput increased by 43%, while lookup latency dropped by 19%.
We plan to reinvest the freed memory into increasing cache capacity without increasing our memory usage, which improves cache hit rates and reduces upstream query volume. We're also exploring further optimizations to the cache itself.
You likely noticed the recent redesign of the Cloudflare Blog. We added dark mode, modernized the look and feel, and made a lot of other small improvements along the way.
What you might not have noticed – well, except for those who are more terminally online – is that the redesign was part of a much bigger migration project. On Wednesday, August 12, we moved the blog to EmDash, a content management system (CMS) built especially to work on Astro and with Cloudflare.
We’ll take you into the migration story – what we learned and how EmDash got better – as well as into the benefits we’re already seeing from a new platform.
We are Customer Zero
At Cloudflare, Cloudflare itself is Customer Zero. This means that we use our products. And – in use – we make them better for ourselves and our customers.
This is a very real cultural value at Cloudflare. The burden of proof is on you if you want to use an external vendor. Why can’t that team support you, what gaps are there, why can’t those gaps be filled, and are those “gaps” true requirements?
This preference is even enshrined in our internal engineering standards, known as our Codex.
We don’t just build products for others; we build them to run Cloudflare itself. We are our own first, most demanding customer.
We validate scale, security, and usability on our own massive infrastructure before a paying customer ever touches the product. If a product breaks, it breaks us first. This forces us to fix issues immediately, ensuring that by the time a feature reaches the enterprise, it has already survived the harshest production environment on earth.
With the launch of EmDash and some limitations with our current CMS vendor, we knew that we’d likely be the Customer Zero for EmDash internally at Cloudflare.
Customer Zero in Action
When we began our initial migration conversations, we started with two main questions:
Does EmDash work for us?
Can EmDash scale?
Does the platform work?
Our first question was the most broad, does EmDash work for us? This is something you’d want to know broadly about any new platform, but especially one that’s pre-1.0.
To answer this question, we ran through a bunch of common user flows, such as:
Publishing and unpublishing a post
Authoring a new post
Scheduling a post
Adding media items
By and large, EmDash held up pretty well to these usability tests. The gaps we found were generally related to:
The biggest oversight we found was around scheduled posts, which didn’t work until EmDash version 0.19.0. This gap was understandable given the early version of EmDash, but it was also definitely something we didn’t want to be finding out after the scheduled time for a post.
Can EmDash scale?
Our biggest concerns were whether our proposed EmDash setup could handle the traffic we saw on the Cloudflare Blog.
The traffic pattern to our blog is incredibly varied. Normal load sits in the neighborhood of 75 requests per second (RPS), but also spikes up to over 5,000 RPS. Some of these spikes line up with the publishing times of new posts, meaning those posts went viral and attracted a lot of attention. Others happen during all points of the day and night, which likely means folks are sending some extra traffic our way, just to see what happens.
Performance also matters for our systems (and our readers). Cloudflare is a web performance company, after all, so the speed at which a page loads becomes incredibly important.
With those two concerns in mind, we built out some scenarios using k6, an open-source performance testing tool:
Ramp: Where we gradually increase requests up to triple the prod baseline and then cool down.
Breakpoint: Where we ramp from 0 to 100 RPS over 10 minutes, stopping when something breaks.
Burst: Where we throw an immediate traffic load of 7,000 RPS and see what happens.
For each of those scenarios, we evaluated:
Availability: Failure when more than 0.01% of HTTP requests lead to 5xx errors, meaning the application couldn’t handle the traffic.
Latency:
P95 latency: Failure when more than 5% of responses exceed 500ms.
P99 latency: Failure when more than 1% of responses exceed 1000ms.
Armed with these tests – and a lot of internal discussion and data points – we came to our production architecture:
EmDash, running on a Cloudflare Worker
Running behind the new Workers Cache (we believe as the first major site to do so)
Using the new EmDash object cache built on Workers KV, which the EmDash team built specifically for our use case.
The multiple layers of caching we put in place play a key role in making the blog both fast and resilient. In the diagram below, they are ordered from top to bottom by proximity to the user:
With this setup, we’re typically serving 99.5% of static files from a cache and 70% of requests from a cache, improving frontend performance and decreasing load on the database.
Once we had that architecture in place, we could start thinking about the frontend redesign as well.
Frontend redesign
Beyond updating the backend architecture, the migration offered us the perfect opportunity to bring the blog's interface into alignment with Cloudflare’s updated visual language. We rebuilt the frontend experience using patterns established by the Kumo design system, creating visual and structural consistency between the Cloudflare homepage, dashboard, and marketing sites. The result is a cohesive reading experience that feels like a natural extension of the broader Cloudflare ecosystem.
A major priority for this redesign, and a long-overdue request from our readers, was native support for light and dark modes. We implemented theme switching tied directly to system preferences, alongside an explicit toggle, and ensured that accessibility guidelines were strictly met across both themes. Regardless of preference, the updated palette and code syntax highlighting adapt seamlessly without sacrificing legibility.
We also took the opportunity to solve a few long-standing user experience quirks, starting with our email subscription form. Previously, the subscription box lived in the top right corner of the page. Because of its placement, readers frequently mistook it for a search bar and typed their search queries directly into the input field.
To fix this, we moved the email sign-up into a dedicated call-to-action block at the bottom of posts.
Now, once a reader finishes an article and wants to stay updated, the prompt to subscribe appears naturally at the end of a post.
Finally, we introduced two dedicated sidebar features on interior post pages to improve navigation and community engagement. On the right, an "On this page" table of contents tracks your progress and lets you jump directly to specific sections of longer technical posts. On the left, a new "Discuss Online" section makes it effortless to share articles and engage in conversations across social platforms and developer communities.
Rollout strategy
As we got nearer to our migration, we started focusing on the broader question of “how do we make this change safely?” Ensuring zero downtime for our readers was a non-negotiable requirement, alongside guaranteeing a seamless fallback mechanism if something went wrong at the last minute.
To achieve this, we deployed a proxy Worker to intelligently route traffic between the legacy blog and the new EmDash-powered site. This Worker set a version cookie on requests, which then let us route incoming traffic to the new or legacy experience accordingly. Additionally, this strategy allowed us to fall back to the legacy blog if the new site experienced any 500 errors. Thanks to the flexibility of Cloudflare Workers, this proxy was relatively simple to create and scaled without any issues. The ability to configure a direct worker-to-worker connection through the NEW_BLOG service binding was particularly useful here, as it reduced latency for any end user going through the proxy. This service binding let the proxy Worker dispatch incoming requests directly to the new blog Worker instead of sending them through a public hostname, DNS, TLS, and an outbound HTTP connection.
On launch day, we initiated a gradual rollout, starting at just 1% of total traffic, then incrementally stepping up to 5%, 15%, and beyond as we validated system health. This phased approach allowed us to observe how the platform handled real-world production load while catching a few last-minute edge cases without impacting the vast majority of our audience. By the end of the day, we had comfortably shifted 100% of traffic over to the new platform.
Results
Measurable performance gains
One of our primary objectives for this migration was to deliver a faster, more reliable site to our readers, and the early data shows we accomplished exactly that.
Comparing p95 response latencies between the old architecture (green line) and the new EmDash setup (yellow line) revealed a stark difference. Where the previous platform experienced periodic latency spikes under load, the new system maintains a remarkably flat, consistent response profile. By running EmDash on Cloudflare Workers alongside our new caching layers, we’ve delivered a significantly faster and more performant reading experience across the board.
We’ve seen all these performance gains – and minimal errors – while serving up to 850 RPS.
MCP servers
With this change, the blog also got more accessible for agents, in two distinct ways.
The first is that we released a new Model Context Protocol (MCP) server for the Cloudflare Blog.
An MCP server bundles up a bunch of specific tools that your agent can then use to interact with an external resource, almost like an API for agents.
Using that MCP, you can now use the following tools with your agents:
search_posts
list_posts
get_post
list_tags
With the new, intuitive EmDash APIs and AI search endpoints exposed by our Worker, creating this new MCP took just a few hours of work.
The second is that – for our blog authors – EmDash has an MCP server for EmDash itself, meaning that they can browse, create, and edit content, publish and schedule posts, remove files, and more.
Though this sort of agentic tooling is becoming more standardized in the CMS industry, what’s not standard is that it’s available without any additional cost. The MCP is just another part of the platform, reflecting a growing trend of designing for agents, as well as humans.
The first test: Agents Week
At Cloudflare, we run multiple innovation “weeks” a year, where we set ambitious goals for internal teams around specific themes. These weeks push our products forward, as well as help customers digest the changes that are constantly happening at Cloudflare.
The latest of these, Agents Week, was quite a test for the new blog. We launched 18 new posts over 9 days. And those posts got a lot of traffic, close to 3 million pageviews.
On the frontend, our new blog Worker did very well, serving up to 450 RPS without any noticeable issues. Thanks to Cloudflare’s built-in DDoS protection, we also absorbed a 28,000 RPS DDoS attack on August 10th, also without any noticeable issues.
On the editing side, we continued to find some issues. Most of these involved small quirks of the editing experience, though we also found some bugs specifically around scheduledposts. We’ve since raised these to the EmDash team and are confident that they’ll be fixed before Birthday Week.
Give EmDash a try
We want to give a heartfelt thank you to the EmDash team, who made this migration about as smooth as possible and were incredibly receptive to our feedback. This is how Customer Zero is supposed to work, and it’s incredibly gratifying to share an inside look into that process with all of our readers as well.
If you’re in the market for a new CMS, try out EmDash today. It’s pretty amazing and – with the upcoming launch to v1 – it’ll be getting even better soon.
In 2021, we shipped Smart Tiered Cache. The idea: for each origin behind your site, Cloudflare picks the single best upper-tier data center to route through, based on real-time latency. Flip one switch, and we find the fastest path from our network to your origin.
That works as long as an origin IP lives in one fixed place. Public cloud origins usually don’t. They sit behind anycast or regional unicast front ends, so one origin IP can look equally close to a dozen Cloudflare data centers at once — and the latency probes have nothing to lock onto. Smart Tiered Cache handles this the safe way: when there’s no clear winner, it falls back to several upper tiers. Nothing breaks. You just lose the thing that made a single closest tier worth it, which is cache efficiency.
Smart Tiered Cache for Public Cloud Regions fixes this by letting you provide a cloud region hint. With that hint, Cloudflare can map public cloud origins to the right region and select better primary and fallback upper tiers, even when the origin IP itself looks anycast or ambiguous.
We made our most popular tiered cache topology smarter
Since it was launched, Smart Tiered Cache has become the most popular tiered cache topology among Cloudflare customers. It’s available to all plans, for free.
Much of our work aims to continually improve it. Over time, we’ve extended Smart Tiered Cache to handle more origin architectures, including:
November 2024: Smart Tiered Cache for R2: We taught Smart Tiered Cache to automatically select the closest upper tier to where the R2 bucket actually lives, reducing latency with zero configuration.
January 2025: Smart Tiered Cache for Load Balancing: We extended Smart Tiered Cache to select a single optimal upper tier for an entire Load Balancing pool, so all origins in the pool share the same cache, improving hit ratios.
Each of these improvements has shared a common goal: understand the customer’s origin infrastructure and automatically do the best thing for that infrastructure.
While we’ve been improving this system for a while, customers still had a common frustration: Smart Tiered Cache did not work when an origin is behind an anycast or regional unicast network, because this architecture prevented us from knowing where the origin is located. And this wasn’t an edge case, either. Origins hosted on public cloud providers behind anycast IPs are a growing slice of the Internet.
Today, we’re closing that gap for origins hosted on AWS, GCP, Azure, and Oracle Cloud.
Why anycast cloud origins are different
Smart Tiered Cache works by measuring the latency from each Cloudflare data center to the origin’s IP address. The data center with the lowest latency becomes the upper tier: the single point through which all cache misses funnel on their way to your origin. By concentrating cache misses at one data center, you get higher cache hit ratios, fewer connections to your origin, and lower latency on origin pulls. This works well when the origin has a fixed, unicast IP address that can be reliably probed.
Many cloud providers use anycast or regional unicast networking for their load balancers, front-end services, and regional ingress points. When we probe these IPs, the origin appears to be “close” to many data centers simultaneously. That is because the IP address represents the cloud provider’s front end, not a single physical origin location. Different Cloudflare data centers may reach different nearby cloud edges for the exact same IP, and the provider then carries the request across its own network to the actual backend. So Smart Tiered Cache cannot confidently pick one best upper tier.
In practice, this could result in hairpin traffic across continents, adding a whole extra round trip. Say your origin sits in Singapore, behind an anycast IP from a cloud provider. Because of how anycast works, our Chicago data center might show the lowest probe latency to that IP. Smart Tiered Cache would then select Chicago as the upper tier. The result: a request from an end user in Asia hits a nearby Cloudflare data center, gets routed cross-continent to the upper tier in Chicago, and Chicago fetches from the origin back in Singapore, crossing the ocean twice. That hairpinning adds hundreds of milliseconds of latency, and it’s one of the most consistently reported issues from customers with cloud-hosted origins.
An example of hairpinning is when traffic is routed to an upper tier in Chicago only to fetch data from an origin in Singapore, resulting in an unnecessary cross-continental round trip.
To address this unnecessary back-and-forth, Smart Tiered Cache learned to detect anycast origins with a constraint from physics: the speed of light. We measure probe latencies from multiple checkpoint data centers around the world to the origin. If the combined latencies from two checkpoint data centers are faster than what light in fiber could physically travel between the two, the origin must be answering from multiple locations, not one. That means it’s anycast.
We detect anycast origins by comparing probe latencies from multiple Cloudflare data centers. If two paths are faster than physically possible for a single origin location, the origin is likely answering from multiple places.
When Smart Tiered Cache detects an anycast origin, it plays it safe: it won’t pin that IP to a single upper tier. Instead, it falls back to a tiered cache topology with multiple upper tiers. Tiered caching still works, but spreading traffic across multiple tiers instead of one means more requests reach the origin. For some setups that’s a fine trade. But if you want one upper tier close to an origin that lives on a public cloud behind anycast IPs, there hasn’t been a good option — until now.
Tell us the region
From the Cloudflare dashboard, go to Caching > Tiered Cache > Origin Configuration. Find your origin IP, click “Set Region Hint,” and tell us the cloud region (for example, aws:us-east-1 or gcp:europe-west1). Smart Tiered Cache takes over from there. Note that, on the dashboard, region hints can only be set for origins whose IPs we’ve detected as anycast.
On the Tiered Cache page, go to the Origin Configuration table and click the edit icon next to an origin IP to set its region hint.
You can set hints one IP at a time, or bulk-edit cloud regions for all your origin IPs at once. Beyond the dashboard, the same configuration is available via the API and through Terraform, so you can integrate it into your existing infrastructure-as-code workflows.
We’re launching with AWS, GCP, Azure, and Oracle Cloud, with more providers coming.
How Smart Tiered Cache for Public Cloud Regions works
Every few hours, we fetch the latest IP range files from each supported cloud provider. These files map every cloud region to its current set of IP prefixes, so when a provider adds, removes, or reassigns a subnet, we pick it up.
Smart Tiered Cache for Public Cloud system diagram
We match those subnets against our upper tier database, which is built from continuous latency probing refreshed every 15 minutes. For each cloud region, each matching subnet contributes a weighted vote based on its current upper-tier assignment. The upper tier with the strongest signal becomes the region’s primary upper tier. Primary and fallback always come from different points of presence (PoPs), so losing one PoP can’t take out both.
Some regions don’t have enough probe data, for example, perhaps the new region’s cloud provider is still rolling out, or the region has no origin onboarded to Cloudflare yet — so there’s nothing to vote on. We fall back to geography: the closest of our Tier 1 PoPs. As origins come online and probe data builds up, the region quietly switches from that geographic guess to the option backed by real data.
Try it now, and what’s next
All this means that the work of selecting the optimal region for your cache — the constant probing, the algorithmic choice of each region’s best upper tier, the geographic fallbacks, the failover across PoPs — runs on our side. Your job is selecting the region hint.
If your anycast origin sits on a public cloud, you can turn this on now. In the dashboard, go to Caching > Tiered Cache > Origin Configuration. Find your origin IP, click Set Region Hint, and pick your region.
Next up, we’re expanding to more providers, and continuing to teach Smart Tiered Cache to recognize more origin setups and pick the right path on its own. To learn more about how Tiered Cache can benefit your service, check out our Tiered Cache documentation.
Today we are launching Workers Cache: a tiered cache that sits in front of your Worker, configured by a single line of Wrangler config and the same Cache-Control headers you already know.
When Workers Cache is enabled, every cacheable request to your Worker hits Cloudflare’s cache first. If there’s a fresh cached response, Cloudflare returns it directly — your Worker doesn’t run, and you don’t pay CPU time for it. On a miss, your Worker runs, and if your response is cacheable, Cloudflare stores it for the next request. The next request from anywhere on Earth can be served straight from cache.
And when content changes, your Worker purges its own cache:
await ctx.cache.purge({ tags: ["product:123"] });
That’s the whole API. There is no zone to configure, no rules engine to set up, no separate cache to provision, and no second product to log into. The Worker’s code is the configuration surface, and the cache follows the Worker wherever it runs — on a custom domain, on workers.dev, behind a service binding, in a preview, in a Workers for Platforms tenant. One Worker, one cache, configured once.
That’s the surface area. There’s a lot underneath: tiered caching across our entire network, full support for stale-while-revalidate so stale responses never block a user, content negotiation via Vary, multi-tenant-safe cache keys via ctx.props, programmatic purges by tag or path prefix, and — the part we think is the biggest unlock — a cache that sits in front of every Worker entrypoint, not just the public one, with per-entrypoint control over which ones cache and which don’t. That last piece means you can compose caching directly into the structure of your app: a chain of entrypoints with cache stages slotted in wherever you want them, configured by the code on either side. We’ll walk through all of it below.
Workers Cache is available today to every Worker on any plan, enabled in Wrangler.
This is the caching API we’ve always wanted Workers to have. Here’s why it took us this long, what becomes possible because of it, and what’s coming next.
Why server-rendered apps need a cache in front
When we introduced Workers in 2017, the pitch was that you could run code on Cloudflare’s network to transform requests on their way to your origin. The Worker sat in front of the cache and the origin:
This was the right model for the use cases we were targeting. If you wanted to add a header to every request, rewrite a URL, do an A/B split, or filter traffic before it reached your origin, putting the Worker in front of the cache and the origin gave you full control over what got cached and what didn’t. Customers built incredible things with it.
But the world changed. Workers stopped being a thing you bolted onto an origin and started being the origin. Frameworks like Astro, TanStack Start, Next.js, Remix, and SvelteKit all ship a Cloudflare adapter that builds your app as a Worker. There’s no origin behind them. The Worker is the server.
When the Worker is the origin, the original architecture has nothing to cache. Every request runs your code, even when the response would be byte-for-byte identical to the one you returned a second ago. The Workers runtime is fast enough that this works — it routinely handles tens of millions of requests per second without breaking a sweat — but “fast enough to render every request” still costs you latency on every page load and CPU time on every invocation. And on a server-rendered app, every page load is, by definition, a render.
Workers Cache flips the architecture. Cloudflare’s cache now sits in front of the Worker:
On a cache hit, your Worker doesn’t run at all. Cloudflare returns the cached response and your CPU billing stays at zero. On a miss, your Worker runs once, populates the cache, and the next request — from anywhere — gets served from cache without invoking your code.
This is what was missing for server-side rendering on Workers. You used to have to choose between two unsatisfying options:
Prerender everything at build time (“static site generation”). Fast page loads, but every change requires a full rebuild and redeploy. For a docs site with a few thousand pages, that’s 5–10 minutes. For a large e-commerce site, it’s worse — and the build runs every single time you touch anything.
Render every page on every request. Up-to-date content, but every page load pays the rendering cost and every visitor pays the latency.
Workers Cache gives you a third option: server-render on demand, cache the rendered response, refresh it on a time-to-live (TTL) you choose. The first request to a new page still renders. Every subsequent request, until the cache expires, is served as if the page were static. When the cache expires, the next request triggers a re-render — and with stale-while-revalidate, even that one doesn’t wait.
You get the speed of a static site without the build time, and the freshness of server rendering without the cost. No framework-specific machinery like Incremental Static Regeneration. Just HTTP caching, working the way it was designed to work, in front of code that was designed to be the origin.
stale-while-revalidate is the part that makes it feel instant
The stale-while-revalidate directive tells Cloudflare that when a cached response expires, it’s allowed to serve the stale copy immediately while it refreshes the response in the background. Cloudflare shipped full support for stale-while-revalidate earlier this year, and it’s the directive that turns “we cache your Worker” into “your Worker’s site feels static.”
Without it, the first request after a cache entry expires has to wait for the Worker to render the page from scratch. The user sees that latency. With it, the first request after expiration gets the stale page immediately (with a Cf-Cache-Status: UPDATING header), and the Worker runs in the background to refill the cache. Every user, including the one who triggered the refresh, gets a cache-speed response.
In practice, this looks like:
 export default {
  async fetch(request) {
    const html = await renderPage(request);
    return new Response(html, {
      headers: {
        "Content-Type": "text/html; charset=utf-8",
        // Treat as fresh for 5 minutes; serve stale for up to an hour
        // while a background refresh runs.
        "Cache-Control": "public, max-age=300, stale-while-revalidate=3600",
      },
    });
  },
};
The mental model that makes this click:
Fresh window (max-age): Cloudflare serves the cached response. Your Worker doesn’t run.
Stale window (stale-while-revalidate): Cloudflare serves the cached response. Your Worker runs in the background to refresh it. No user waits.
Outside both windows: Cloudflare runs your Worker to generate a fresh response, and the user waits for that one render.
You pick the windows. For a product catalog that updates every few minutes, max-age=300, stale-while-revalidate=3600 means visitors basically never wait, and your Worker still runs often enough to keep content fresh. For a blog archive that almost never changes, max-age=86400, stale-while-revalidate=2592000 means your Worker runs once a day per page.
The first request to a brand-new page is the only one that pays the full render cost. After that, the page behaves like static output for visitors, while your Worker still owns how the page gets generated.
One URL, many representations: Vary works
Real apps rarely return the same bytes to every client. The same product page might be HTML for a browser and JSON for an API client. The same image might be WebP for clients that support it and JPEG for the ones that don’t. The same homepage might come back in English, French, or Japanese depending on the user.
Doing this without a cache is easy — your Worker just reads the request header and returns the right thing. Doing it with a cache is where it usually gets ugly. Most caches give you two bad options: cache nothing on URLs that have multiple representations, or cache one representation and serve it to everyone.
Workers Cache supports the standard HTTP Vary header, which is the right way to solve this. When your Worker returns a response with Vary: Accept-Encoding (or Accept, or Accept-Language, or any other request header), Cloudflare stores a separate cached variant per distinct combination of those headers — and only returns a variant whose stored values match the incoming request.
One URL, two cached variants. A browser that sends Accept: image/webp,*/* gets the WebP. A browser that sends Accept: image/jpeg gets the JPEG. Both come from cache. Your Worker writes both variants on the first request to each, and then runs zero times for either after that.
This is the well-trodden HTTP standard for content negotiation, and Workers Cache implements it the way RFC 9110 and RFC 9111 describe. There’s no allowlist of what headers you can Vary on. You list whatever you need, and Cloudflare keys variants on the verbatim values. The docs go through the edge cases — how to keep variant fan-out under control by normalizing headers in a gateway Worker, why purges invalidate all variants of a URL together, and the one case (Vary: *) that disables caching entirely.
This is your Worker’s cache, not your zone’s
Before we get to what becomes possible with all this, there’s a conceptual shift worth naming.
Cloudflare has had a cache forever. It’s configured at the zone level: Cache Rules, Page Rules, the cached-file-extensions list, Cache Reserve, Tiered Cache topology, custom cache keys. All of it is set per zone, and historically a Worker had to either fit into that zone’s configuration or work around it.
Workers Cache is different. It’s your Worker’s cache — it belongs to the Worker, not to a zone. This has a bunch of consequences that turn out to matter:
There is no zone configuration to manage. Cache Rules, cache level settings, the file-extensions list, Page Rules — none of them apply to Workers Cache. The Worker’s Cache-Control headers are the configuration.
The cache follows the Worker, not the hostname. A Worker that’s bound to api.example.com, api.example.net, and invoked over a service binding shares one cache across all three. A request to /users/42 hits the same cached entry regardless of which way in it came.
The cache works on workers.dev. It works in preview URLs (each preview gets its own cache, so testing a change doesn’t poison production). It works in Workers for Platforms (each user Worker has its own cache, isolated from the dispatcher and from other tenants). All of these used to be second-class citizens for caching. They aren’t anymore.
Purges are scoped to the Worker’s entrypoint. When you call ctx.cache.purge({ purgeEverything: true }), you’re only purging your Worker entrypoint’s cache. No risk of nuking your zone’s other content. No risk of one Worker’s deploy invalidating another’s data.
What you configure about caching, you configure in code: which paths get longer TTLs (branch on the path and set a different max-age), which requests bypass the cache (return Cache-Control: private), how the cache key is shaped (control what gets into ctx.props, normalize the URL in a gateway Worker before dispatching). The Worker you already wrote is the configuration surface.
Workers Cache is regionally tiered by default. There are two layers:
A lower tier in the Cloudflare data center closest to the user. Every data center that receives traffic for your Worker has its own lower-tier cache.
An upper tier that aggregates fills across the whole network. There are fewer of these, and every lower tier consults the upper tier on a miss.
A request hits the lower tier first. On a hit, the response is served and that’s the end of it. On a miss, the lower tier asks the upper tier. On a hit there, the response is returned and also stored in the lower tier on the way back. Only if both tiers miss does your Worker actually run — and the response from that run gets stored in both tiers.
The reason this matters is that the first request anywhere in the world populates the upper tier. Every subsequent request, from any data center, can be served from the upper tier without your Worker running — even if the lower tier at that data center has never seen the request before. Cache hit ratios are dramatically higher than they would be with a single flat cache layer, which is exactly what you want when your Worker is the origin.
This is the same topology that powers Tiered Cache for zones today, except you don’t configure it. There is no dialog for “turn on tiered cache for my Worker.” Every Worker that has caching enabled gets tiering for free.
If your Worker uses Smart Placement, the cache composes cleanly with it: tiers are consulted first, and only if both miss does Smart Placement route execution close to your origin. We have more to say about how those layers interact, including a few rough edges we’re planning to smooth out, in the docs.
Run your app near the user and near the data
There’s a recurring tension in web performance that nobody has fully resolved: you want your code to run close to the user (because the round-trip between user and server is on the critical path), and you want your code to run close to the data (because every database query is also a round-trip). Pick one, and the other gets slow.
We’ve spent years chasing both. Our network puts us within ~50ms of about 95% of the world’s Internet users. Smart Placement and Placement Hints let you keep your code close to your data without ever having to think about cloud regions. But until now, the two pieces didn’t fully compose. You could do “near the user” or “near the data,” and if you wanted both halves of your app to be in the right place at the same time, you had to be a Cloudflare expert. We knew we could do better.
Workers Cache is the piece that closes the gap. Because the cache belongs to the Worker (not the zone), and because service bindings and ctx.exports calls between Workers go through the cache, you can build an app as a chain of Workers — each one running where it should run — with the cache as the seam between them.
The architecture looks like this:
Worker A runs near the user. It handles the cheap, latency-sensitive parts of every request: authentication, rate limiting, routing, header normalization, rendering the outer “shell” of an HTML page that doesn’t depend on data.
Worker B runs near the data, courtesy of Smart Placement or an explicit Placement Hint. It does the heavy work: server-rendering pages that fetch data, reading product catalogs, generating search results, aggregating APIs, expensive transforms.
Workers Cache sits in front of Worker B. When Worker A calls Worker B over a service binding, Cloudflare checks Worker B’s cache first. On a hit, Worker A receives the response and Worker B doesn’t run at all — no data-center hop, no database query, no rendering work.
The cache hit path becomes: user → Worker A near the user → cache hit for Worker B → response. The data hop is paid only on a miss. Your hot pages run at the speed of code-in-front-of-the-user, and your cold pages still benefit from running near the data when they do execute.
You don’t have to architect anything special to get this. Write your app as two Workers, point one at the other with a service binding, turn caching on in Worker B’s wrangler.jsonc file, and you’re done.
Multi-tenant by default, with ctx.props
If you’re caching a Worker that returns user-specific data — say, an API that serves different content per logged-in user — you need a way to make sure one user can never see another user’s cached response. The standard solution is “don’t cache authenticated requests,” and Cloudflare’s automatic bypass for Authorization headers does exactly that. But “don’t cache anything” gives up the entire performance win.
Workers Cache solves this by making the caller’s ctx.props part of the cache key. When one Worker calls another over a service binding and passes ctx.props with a user ID, tenant ID, or any other identifier, callers with different props get separate cache entries. One user’s response can never leak into another user’s cache.
import { WorkerEntrypoint } from "cloudflare:workers";

interface Props { userId: string; }

export default class Backend extends WorkerEntrypoint<Env, Props> {
  async fetch(request: Request): Promise<Response> {
    // ctx.props.userId is part of the cache key. User A and User B
    // requesting the same URL get separate cached entries.
    const { userId } = this.ctx.props;
    const data = await loadUserData(userId);

    return new Response(JSON.stringify(data), {
      headers: {
        "Content-Type": "application/json",
        "Cache-Control": "public, max-age=300",
      },
    });
  }
}
The typical pattern is to authenticate the request in a gateway Worker, strip the Authorization header, set the authenticated user’s ID into ctx.props, and then call the cached backend Worker. The gateway runs on every request (it has to, to authenticate), but the expensive backend only runs when there’s no cache entry for that user yet. Auth’d APIs go from “uncacheable” to “cached per user with full safety,” and the cache key does the isolation for you. The docs walk through this in detail in Multi-tenant safety with ctx.props and the example in Per-user authenticated responses.
Other CDNs make you choose between correctness and hit ratio: key the cache by each user’s token, or send every request back to origin for authorization. Workers Cache lets you share cached API responses at the edge while preserving per-request authorization boundaries. We don’t know of another CDN that offers this as a built-in model for authenticated, multi-tenant APIs. We’re pretty proud of it.
A cache between every Worker entrypoint
Here is the part of Workers Cache that we think is the biggest unlock, and it’s the part that’s hardest to see if you’re thinking about it as “a CDN cache that happens to work in front of Workers.”
Workers Cache sits in front of every Worker entrypoint — the default export, every named WorkerEntrypoint, and every call between entrypoints in the same Worker via ctx.exports. That last clause is the one that changes what you can build.
When one entrypoint calls another via ctx.exports, the cache evaluates that call the same way it would evaluate a request from a browser. A hit returns the cached response and the callee never runs. A miss runs the callee and stores its response under its own cache key — keyed by the callee’s entrypoint, path, query string, and ctx.props. The caller still runs on every request, but anything it hands off to the callee is memoized independently.
You decide, per entrypoint, which ones cache. In your Wrangler config, the exports map lets you turn caching on or off for each entrypoint by name ("default" is the default export). Opt an entrypoint in to cache the responses it produces; opt one out to keep it running on every request. A gateway or router entrypoint — anything that authenticates, normalizes, or dispatches — should be opted out, so it always runs, and its own output is never served from cache.
That gives you a primitive you can compose. You can author a Worker as a chain of small entrypoints — auth, normalization, routing, the expensive read, the data layer — and let Workers Cache slot in wherever you want it. Each cached entrypoint is a unit of memoization with its own key, its own TTL, and its own tag namespace for purging. Anything you would want to configure about caching — when it runs, what it keys on, when it invalidates — is expressed as ordinary Worker code: which entrypoint you call, what request you forward, what ctx.props you pass, what Cache-Control you set.
To make this concrete, here’s a single Worker that does three things you couldn’t easily do together on any other platform: it authenticates every request, caches the expensive backend behind a multi-tenant-safe cache key, and invalidates that cache when data changes.
Caching is configured per entrypoint. The gateway must run on every request — both to authenticate and because a cached gateway response would skip that auth check — so we disable caching on the default entrypoint and enable it only on the inner one:
import { WorkerEntrypoint } from "cloudflare:workers";

interface Env { API_TOKEN: string; }
interface Props { userId: string; }

// Inner entrypoint: the expensive work. Workers Cache sits in front
// of this — on a hit, this code never runs.
export class CachedBackend extends WorkerEntrypoint<Env, Props> {
  async fetch(request: Request): Promise<Response> {
    // ctx.props.userId is part of the cache key, so this is cached
    // separately for every user.
    const { userId } = this.ctx.props;
    const data = await loadExpensiveData(userId);

    return new Response(JSON.stringify(data), {
      headers: {
        "Content-Type": "application/json",
        "Cache-Control": "public, max-age=300, stale-while-revalidate=3600",
        "Cache-Tag": `user:${userId}`,
      },
    });
  }

  // Invalidate a user's cached response. purge() is scoped to the
  // entrypoint that calls it, so it must run inside CachedBackend —
  // the entrypoint that owns the cached response.
  async invalidate(userId: string): Promise<void> {
    await this.ctx.cache.purge({ tags: [`user:${userId}`] });
  }
}

// Outer entrypoint: runs on every request to authenticate and route.
// Caching is disabled for it in Wrangler config (above), so it always
// runs and the auth check is never skipped by a cache hit.
export default {
  async fetch(request, env, ctx): Promise<Response> {
    const userId = await authenticate(request, env);
    if (!userId) return new Response("Unauthorized", { status: 401 });

    // Invalidate this user's cache on writes, from the entrypoint that
    // owns it.
    if (request.method === "POST") {
      await handleWrite(request, userId);
      await ctx.exports.CachedBackend.invalidate(userId);
      return new Response("OK");
    }

    // For reads: strip Authorization (otherwise Cloudflare's automatic
    // bypass fires and nothing caches), then dispatch to the cached
    // backend with the authenticated user's identity in ctx.props.
    const forwarded = new Request(request);
    forwarded.headers.delete("Authorization");

    return ctx.exports.CachedBackend.fetch(forwarded, {
      props: { userId },
    });
  },
} satisfies ExportedHandler<Env>;
The whole thing is one Worker. One source file. One deploy. But there are two execution stages — caching is turned off for the gateway and on for the backend in one small exports block — and a cache sits between them, keyed per user, invalidated by the write path, and serving stale during background refreshes. The cache stage isn’t something you bolted on. It’s a layer of the program, written in code.
The patterns this composes into are open-ended. The same shape works for:
Caching a Durable Object. Wrap the Durable Object behind an entrypoint, set Cache-Control on the response, and reads stop touching the Durable Object on a hit. Writes go to the DO directly and purge the cache by tag. The DO stays unaware that caching is happening.
Normalizing Accept-Encoding before Vary. The outer entrypoint restores the original encoding from request.cf.clientAcceptEncoding (Cloudflare’s front line normalizes it for cache efficiency) and forwards to a cached entrypoint that varies on the real value. Hit ratios stay high; clients get the right encoding.
Stripping tracking parameters before caching. The outer entrypoint canonicalizes the URL — or sets a custom cache key with cf.cacheKey on the ctx.exports call — so the cached inner entrypoint sees only the canonical form, and ?utm_source=anything collapses to a single cache entry.
Stack them. A single Worker can have an outer entrypoint that authenticates and routes, a normalization entrypoint that strips tracking parameters and restores encoding headers, a cached entrypoint that fronts a Durable Object, and a separate cached entrypoint for an unauthenticated public API — each connected by a cache stage you didn’t configure, just decided where to put. The Examples page in the docs walks through several of these end-to-end.
We don’t know of another platform where you can do this. CDN caches sit in front of an origin. Function platforms run functions. We don’t know of another platform that gives you a cache that sits inside a single deployable unit, between the parts of your application, with each cache stage configured by the code on either side of it. That’s what Workers Cache is. And because it composes with everything else the platform already gives you — Smart Placement, Durable Objects, service bindings, ctx.props, ctx.exports — the patterns you can build are open-ended. We’ve barely scratched the surface in this post.
First-class support in your framework
If you’re building with Astro, the Cloudflare adapter wires up Workers Cache for you. Just add the cacheCloudflare provider to your configuration:
The adapter enables the cache, sets the right headers on the responses Astro generates, attaches Cache-Tag values for invalidation, and gives you a cache.invalidate() helper for purging tags when content changes. Astro pages that opt into server rendering automatically get the “render once, cache, refresh in the background” flow described above — no per-route configuration required, no framework-specific runtime layer to learn.
We’re working with the maintainers of other frameworks to ship the same integration. If you build a framework adapter for Cloudflare, the Workers Cache APIs are exactly what you’d want them to be — header-driven configuration, programmatic purges, no platform-specific concepts to model.
See your cache on the same dashboard as your Worker
Caching is only useful if you can see what it’s doing. The Workers Observability dashboard now surfaces cache hit information per invocation:
You can see, per Worker:
Cache hit ratio over time. The number you want trending up after you enable caching.
Hits, misses, updates, bypasses broken down. If your hit ratio is low, this is where you find out why — too many BYPASS responses (because something is setting a cookie?), too many MISS responses (because the cache key is partitioning more than you thought?), too many UPDATING responses (because max-age is shorter than your traffic interval?).
Because all of this lives on the same dashboard as your Worker’s other observability — logs, exceptions, CPU time, request counts — you don’t have to context-switch between looking at your zone and your Worker to understand what’s happening.
Billing
Cache hits don’t run your Worker, and they don’t bill CPU time. They do count as a request at the standard Workers request rate, the same as any other invocation. Cache misses and bypasses bill normally — request + CPU time, exactly as they would without caching.
Outcome
Request charge
CPU time charge
Cache HIT (Worker does not run)
Standard rate
Not billed
Cache MISS (Worker runs)
Standard rate
Billed
Cache BYPASS (Worker runs)
Standard rate
Billed
Static asset request
Standard rate
Not billed
Worker-to-worker invocation
Standard rate
Billed if the Worker runs
There’s no separate Workers Cache SKU and no per-GB cache storage fee. Tiered caching, purges, stale-while-revalidate, and the analytics described above are all included. If a request would have run your Worker and Workers Cache serves it as a hit instead, you still pay the standard request rate, but you pay no CPU time for that request. Because of this, that cache hit costs less than rendering the same response in your Worker.
One thing to watch: when caching is enabled, requests that are normally free — static asset requests and worker-to-worker invocations through service bindings or ctx.exports — are billed at the standard request rate, because each one now consults the cache in front of your Worker.
What’s next
Things we know we want to do next:
Smarter co-location with Smart Placement. Today, Cloudflare chooses the upper-tier cache and Smart Placement target separately. On a full miss, the request may travel between Cloudflare locations twice: once to check the upper tier, and again to run your Worker near its data. We’re working to coordinate those choices, so a miss only makes that long-distance trip once.
Larger response size limits. At launch, all responses follow the Free plan’s cacheable size limit (512 MB), regardless of your account. That’s temporary — the standard per-plan cache limits will apply once we finish a few rollout steps.
An API to mark cached responses stale. ctx.cache.purge() removes matching responses from cache. We’re looking at a ctx.cache.invalidate() API that makes matching responses behave as expired, so the next request can still get a fast stale response with stale-while-revalidate while your Worker refreshes the cache in the background.
Try it
Workers Cache is available today to every Worker on any plan.
Long integrated development environment (IDE) sync/indexing times can quietly erode developer productivity, making code navigation sluggish, spiking memory usage, and slowing down Jetpack Compose preview updates, turning the IDE into a bottleneck rather than a helpful tool. For Android engineers working in a large monorepo, this was a daily reality. In this post, we will share how we built a custom Focus plugin that dramatically reduced Android Studio sync times by leveraging our existing investments, such as the Gradle-to-Bazel migration workflow.
Our Android monorepo at scale
The Grab passenger Android (PAX) repository contains roughly 2,000 Android modules and 11,000,000 lines of code. As the repository grows year over year, a natural consequence of scaling our superapp, which combines ride-hailing, food delivery, payments, and more into a single application, is the increase in time required to build and sync the project.
What makes this growth especially pronounced today is the shift in how code gets written. Development assisted by artificial intelligence (AI) has enabled engineers to produce more code faster than before. At the same time, non-engineering personnel such as designers, product managers, and other non-technical contributors have started making changes to low-risk features under engineering provision. Together, these two forces are pushing the codebase to grow at its fastest rate ever, which in turn compounds the pressure on every developer’s IDE and build tooling to keep up.
We previously adopted Bazel to speed up incremental and cached builds, but build time was only part of the picture. We intentionally kept Android Studio syncing with Gradle, so developers get fast Bazel builds while the IDE uses the standard Gradle toolchain, thereby preserving compatibility and avoiding the friction and tooling gaps of full Bazel IDE integration. This trade-off gives us the best of both worlds, but it also means Gradle sync remains a first-class concern. Even though Bazel handles the builds, Android Studio still depends on Gradle sync to import the project model that powers IDE features such as code navigation, autocompletion, and error highlighting. That sync process, which evaluates every module declared in settings.gradle, had quietly become a major pain point.
The problem
Over time, we noticed a growing number of reports stating that IDE syncs were too slow and memory-intensive. A single full sync could take more than 35 minutes on a cold start. The pain was especially acute after a rebase or branch checkout. Since these operations often modify build configuration files, Android Studio would detect the changes and trigger a full re-sync just to restore basic IDE functionality.
We conducted a developer experience survey to quantify the issue. From 55 responses, the results painted a clearer picture:
76% said long sync times significantly or very significantly impacted their productivity.
60% were unsatisfied or very unsatisfied with IDE sync time.
47% were unsatisfied or very unsatisfied with Compose preview update speed.
82% said they would benefit from the option to exclude modules from syncing.
Figure 1. Results of developer experience survey.
The survey validated our anecdotal feedback: developers were frustrated. Slow, sluggish IDE performance was eroding productivity and disrupting flow. We set out to determine whether developers really needed to load every module to work on just one.
Investigation
Root cause
The root cause was straightforward: module count. With roughly 2,000 modules in the codebase, a full sync required Gradle to configure every single module, including parsing build files, resolving dependencies, and generating IDE project models, regardless of whether the developer actually needed them. A developer working on the Payments feature still had to wait for Gradle to process Food, Transport, Mart, and every other module. The configuration time and resulting memory consumption grew roughly in proportion to module count, and the count kept rising.
Exploring community solutions
We looked at existing solutions in the Android community. One promising candidate was the Focus plugin from Dropbox. Here’s how the Focus plugin works:
The developer runs a Gradle command to focus on a specific module (e.g. ./gradlew :module:focus).
The Gradle task calculates the dependency graph, generates a separate focused settings file, and writes a .focus marker file that tells Gradle to use it instead of the full project settings.
The developer syncs the IDE, which now only configures the focused modules.
This approach works because instead of syncing the entire repository, the developer only configures the module they are working on, along with its required dependencies. Everything else is excluded.
For example, if you are working on the Payments module, only Payments and its dependency chain get loaded. Food, Transport, and Mart modules are excluded entirely.
Figure 2. Focus mode sync vs. full sync.
Depending on the size of the target module, this approach can cut the number of loaded modules by 50% or more, especially with a well-structured modularization architecture. We wanted to adopt this approach and saw an opportunity to improve it further by leveraging our existing Gradle-to-Bazel migration workflow.
Our solution: Building a custom Focus plugin
The Dropbox Focus plugin was a great starting point, but it introduced several friction points in our setup:
We would need to move all non-essential declarations from settings.gradle into a separate settings-all.gradle file.
We would need guardrails to ensure new modules are declared in the correct file.
Most critically, focusing on a module requires running a Gradle task (e.g., ./gradlew :module:focus), which itself goes through Gradle’s configuration phase and adds a noticeable delay before a developer can even start an IDE sync.
We set out to address each of these issues.
Challenge 1: Eliminating the configuration phase
The Dropbox Focus plugin recalculates the dependency graph every time a developer runs the focus command. This means every Focus operation pays the cost of Gradle’s configuration phase, parsing every build.gradle file in the project to resolve the full dependency tree.
We realized we already had this information. Our build infrastructure includes Grazel, which migrates Gradle build files to their Bazel equivalents via a migrateToBazel task, and our Continuous Integration (CI) validations ensure that both are aligned. This task already traverses the full dependency graph for migration purposes.
Our insight: generate a dependency graph as a static file during migrateToBazel and reuse it for focus operations.
Figure 3. Focus flow vs. Grab’s customized focus flow.
By pre-computing and persisting the dependency graph, we skip the Gradle configuration phase entirely. The focus operation becomes a fast, local file lookup instead of a lengthy Gradle computation. The developer simply selects their module and syncs.
The dependency graph is stored as a JSON file, which is lightweight and fast to read. The trade-off is that it requires a migrateToBazel run to stay up-to-date. When creating a new module or changing module dependencies, developers need to rerun ./gradlew migrateToBazel to regenerate the graph. We accepted this because developers already had to run migrateToBazel before merging to master (to ensure Bazel files are current). The graph stays fresh as part of their existing workflow, and no extra step is required.
Challenge 2: Minimizing developer friction with a Gradle plugin
We did not want to introduce a process that adds cognitive load. Migrating all module declarations to a new settings.gradle file would require every team to change their workflow. Instead, we adopted a more elegant approach.
The include shadow trick
In a standard Android project, modules are declared in settings.gradle using the include function:
include 'app'
include 'payment'
include 'food'
// ... hundreds more
The include function is part of the Gradle Settings API. In Groovy, you can define a local closure variable with the same name as an existing method. Since Groovy resolves local variables before delegate methods, the closure effectively shadows the original include method and all subsequent include calls in the script invoke the closure instead.
We created a custom Gradle plugin with a focusInclude function that decides whether to include or exclude a module based on the current focus configuration. By adding just three lines to the top of settings.gradle, we redirect all include calls through our plugin:
// After applying the focus plugin in the buildscript block
def include = { module ->
 com.grab.focus.GradleFocusPluginKt.focusInclude(settings, module)
}
include 'app'
include 'payment'
include 'food'
The rest of the file remains untouched. Every existing include call now passes through focusInclude, which checks whether the module should be loaded based on the developer’s focus selection. If no focus is active, all modules are included as usual with zero behavior change.
This approach meant zero migration effort for feature teams. The settings.gradle file stays as-is, and the plugin integrates seamlessly.
Early implementation: Property-based focus
In the early days of this plugin’s development, the way to specify focus modules was via a Gradle property in the command line:
./gradlew build -Pmodules-to-sync=":app,:payment"
The focusInclude function reads this Gradle property. If present, it activates focus mode and only includes the specified modules (and their transitive dependencies resolved from the graph file). If absent, all modules are included normally.
Challenge 3: Making it seamless with an Android Studio plugin
Figure 4. User flow.
Manually passing Gradle properties on the command line was functional but not ideal. We needed a better developer experience. The Gradle property approach opened the door to IDE integration; this led to an Android Studio plugin (an IntelliJ plugin) being built that automates the entire flow through a user interface (UI):
Module selection: The plugin presents a list of all available modules, parsed from the pre-computed dependency graph file. Developers select which modules they want to work on.
Dependency count indicator: Since we have the full dependency graph, the plugin displays how many transitive dependencies each module requires. This gives developers immediate visibility into module “weight” and encourages teams to keep their modules lean.
Automatic argument injection: The plugin uses two IntelliJ Gradle extension points to inject the -Pmodules-to-sync property: a GradleResolverExtension that adds the argument during project sync, and a GradleTaskManagerExtension that injects it before any Gradle task execution (including Compose preview builds). The developer just clicks sync; the plugin handles the rest.
Figure 5. Example of Automatic Argument Injection.
Beyond the core functionality, we added several usability enhancements to the plugin:
Indirect focus indicator: Modules that will be synced as a transitive dependency of a focused module are marked as “indirectly focused,” giving developers visibility into exactly what will be loaded.
Search and filtering: With hundreds of modules, finding the right one matters. The plugin supports fuzzy matching and regular expression (regex) search to quickly narrow down the module list.
Sort by dependency count: Modules can be sorted by name or by dependency count, making it easy to spot the heaviest modules at a glance.
Status bar widget: A persistent “Focus: X/Y” indicator in the IDE status bar shows how many modules are currently focused out of the total, with a click-through to the Focus tool window.
State persistence: The developer’s focus selection is saved and restored between IDE sessions, so they do not need to reselect modules after restarting Android Studio.
Encouraging lean module architecture
An unplanned but welcome side effect of the focus plugin was that it nudged teams toward a cleaner module architecture. With dependency counts now visible in the IDE, developers became more aware of their module’s size, which in turn encouraged a clearer separation between interface and implementation.
Interface module (e.g., :payment-api): Contains only the public API definitions (interfaces, data classes, contracts). This is the module that other teams depend on. Because it has no implementation details, it carries very few transitive dependencies.
Implementation module (e.g., :payment-impl): Contains the actual implementation of those interfaces. This module typically has a larger dependency footprint, but only the owning team needs to load it.
By depending on the interface module rather than the implementation module, teams avoid pulling in a large tree of transitive dependencies. This keeps the dependency count low for consumers, which directly translates to faster focus sync times and leaner Compose preview builds.
How we measure
Instrumentation: The PAX IDE plugin
The PAX IDE plugin is a mandatory install for every PAX Android engineer in Grab. This gives us a consistent, organization-wide data collection baseline without requiring any opt-in. The plugin registers four IntelliJ Platform listeners that automatically capture metrics on every relevant IDE event:
IntelliJ API
What it tracks
GradleSyncListenerWithRoot
Sync time
ProjectIndexingActivityHistoryListener
Indexing time
ProjectIndexingActivityHistoryListener
Scanning time
PerformanceListener
IDE freezes
Each metric event is enriched with shared context captured at event time: IDE version and build number, heap memory usage, focus state (enabled/disabled, number of focused modules), Operating System (OS) info, and project name. This means every data point is automatically segmented by whether focus mode was active, which is exactly what we need for before/after comparisons.
What each metric captures
Sync time: We implement GradleSyncListenerWithRoot and calculate wall-clock duration from syncStarted() to syncSucceeded() or syncFailed(). This covers the full Gradle configuration, dependency resolution, and IDE model generation phase.
Indexing time: ProjectIndexingActivityHistoryListener.onFinishedDumbIndexing() provides a ProjectDumbIndexingHistory object. We read history.times.totalUpdatingTime, the time IntelliJ spent updating its symbol index after the sync.
Scanning time: ProjectIndexingActivityHistoryListener.onFinishedScanning() provides a ProjectScanningHistory object. We read history.times.totalUpdatingTime and history.times.scanningType (full vs. partial) for additional segmentation.
IDE freezes: PerformanceListener.uiFreezeFinished(durationMs) is called by the platform whenever the Event Dispatch Thread (EDT) is blocked long enough to be classified as a freeze. The duration arrives directly as a parameter.
IDE memory usage: Captured at the moment of each metric event via Runtime.getRuntime(). Captures used memory (totalMemory – freeMemory) and max heap. Attached to every event as part of the shared context.
IDE version: From ApplicationInfo.getInstance(), captures version name, full version string, and build number. Also attached to every event, enabling per-version breakdowns.
Survey
After each successful sync, the plugin triggers an in-IDE notification prompting developers to fill out a short survey. The notification respects developer attention; it uses a weekly reset cycle with a “Don’t remind me again” option that appears after the second prompt. These periodic qualitative check-ins complement the telemetry data and help surface pain points that raw numbers alone may not capture.
Establishing the baseline
The plugin collects focus_enabled on every event. Therefore, baseline numbers come directly from the same pipeline; they are simply the subset of metric events where focus_enabled = false. This means the before/after comparison is an apples-to-apples measurement from the same instrumentation, same engineers, same codebase, with no separate manual benchmarking required.
Results
Compose preview build
The focus approach also improved Jetpack Compose preview builds. Compose previews require a module build to render, and with fewer modules loaded, the IDE has significantly less indexing overhead. A typical UI module has just 5–10 local dependencies. With the focus plugin, a developer configures only those modules instead of all 2,000. Developers consistently report that Compose previews feel significantly more responsive in focus mode.
As a best practice, we recommend that teams separate their UI into dedicated modules containing only composable functions and minimal dependencies. This maximizes the benefit of focus mode for preview builds.
Memory usage
In focus mode, excluded modules are not configured by Gradle and not indexed by the IDE, significantly reducing both build-process and editor memory consumption from approximately 10 GB down to 2 GB. This frees up memory for Bazel builds and other tooling. Developers reported fewer freezes, faster code navigation, and more responsive autocompletion.
Sync time
We observed a dramatic reduction in per-sync IDE sync time. A full sync previously took around 26 minutes at the 95th percentile (p95). With the Focus plugin, sync times dropped to under 2 minutes for typical feature work. The p95 remains higher for modules with deep dependency trees, but in practice, sync times vary significantly depending on module size. A typical UI module with 5 to 10 dependencies syncs in roughly 2 minutes, while heavier modules with deep dependency graphs take longer. For most developers working on focused feature work, the improvement is dramatic.
Tradeoffs
Focus mode does come with limitations. IDE features like “Find Usages” and cross-module refactoring only cover the focused modules; developers occasionally need to expand their focus set or temporarily switch to a full sync for repo-wide operations. In practice, this has been a minor inconvenience compared to the productivity gained.
Conclusion
IDE sync time is one of those problems that slowly degrades the developer experience without a single dramatic breaking point.
Our solution combined three key ideas:
Reuse existing infrastructure: By generating the dependency graph during migrateToBazel, we eliminated the expensive Gradle configuration phase without adding a new build step.
Minimize adoption friction: The Groovy include shadow trick let us integrate the focus mechanism with just three lines of code, requiring zero changes from feature teams.
Invest in user experience (UX): The Android Studio plugin turned a manual, error-prone process into a one-click operation with useful module health indicators.
The results spoke for themselves. IDE sync time dropped from 35 minutes to under 1 minute (depending on module size). IDE memory consumption fell from 10 GB down to 2 GB, freeing up headroom for Bazel builds to run alongside the IDE. Compose preview update times improved significantly due to reduced indexing overhead. And adoption was frictionless. Engineers went from a manual, multi-step process to a simple Select → Focus → Sync flow with native IntelliJ integration.
As the codebase continues to grow, accelerated by AI-assisted development and a broader contributor base, we are also investing in guardrails to keep quality in check. An area we are actively exploring is using skills.md to guide AI coding agents when they generate new modules, encoding architectural conventions and dependency rules directly into the context that AI tools consume. This helps ensure that AI-generated code lands in the right shape from the start, rather than accumulating structural debt that compounds the sync and build problems described above.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
At Cloudflare, we are heavy users of ClickHouse, an open-source analytical database management system. We redesigned one of our largest ClickHouse tables to add a column to the partitioning key. The change enabled per-tenant retention on a table that serves hundreds of internal teams. The design went through several rounds of revision and review with engineers across multiple teams before we landed on the final approach. But a few weeks after rollout, the jobs that produce most of Cloudflare’s bills were running up against their hard daily deadline.
All the usual suspects looked clean: I/O, memory, rows scanned, parts read. Everything we would normally check when a ClickHouse query is slow appeared to be normal. The problem turned out to be lock contention in query planning, something we’d never had reason to look for before.
This is the story of how this migration exposed a hidden bottleneck in ClickHouse’s internals, and the patches we wrote to fix it.
The setup: a petabyte-scale analytics platform
We use ClickHouse to store over a hundred petabytes of data across a few dozen clusters. To simplify onboarding for our many internal teams, we built a system called “Ready-Analytics” in early 2022.
The premise is simple: instead of designing new tables, teams can stream data into a single, massive table. Datasets are disambiguated by a namespace, and each record uses a standard schema (e.g., 20 float fields, 20 string fields, a timestamp, and an indexID).
In ClickHouse, the way data is sorted is crucial to query performance. This is where the indexID comes into play. It’s a string field, which forms part of the primary key, meaning that every individual namespace can have its data sorted in a way that is optimal for the queries the owners of that namespace expect to be running. Altogether, we end up with a primary key that looks like this: (namespace, indexID, timestamp).
This system is popular, with hundreds of applications using it. It had already grown to more than 2PiB of data by December 2024, and an ingestion rate of millions of rows per second. But it had one critical flaw: its retention policy.
The problem: one retention policy to rule them all
Cloudflare has been using ClickHouse for many years, since before it had native Time-to-Live (TTL) features. Consequently, we built our own retention system based on partitioning. The Ready-Analytics table was partitioned by day, and our retention job simply dropped partitions older than 31 days.
This “one-size-fits-all” 31-day retention was a major limitation. Some teams needed to store data for years due to legal or contractual obligations, while others needed only a few days. This restriction meant these use cases couldn’t use Ready-Analytics and had to opt for a conventional setup, which has a far more complex onboarding process.
We needed a new system that allowed per-namespace retention.
The solution: a new partitioning scheme
We considered two main approaches:
A Table-per-Namespace: This would naturally solve the retention problem but would require significant new automation to manage thousands of tables on demand.
A New Partitioning Key: We could change the partitioning key from just (day) to (namespace, day).
We chose the second option. This would allow our existing retention system to continue managing partitions, but now with per-namespace granularity.
We knew this would increase the total number of data parts in the table, but we made a key assumption: since every query is filtered by a specific namespace, the number of parts read by any single query shouldn’t change. We believed this meant performance would be unaffected.
This shows how we changed the partitioning, allowing us to cheaply drop data for a single namespace
This new system also allowed us to build a sophisticated storage management layer. Using themax-min fairness algorithm, we could set a target disk utilization (e.g., 90%) and automatically “share” available space. Namespaces using less than their fair share would cede their unused capacity to those that needed more. This allowed us to confidently run our clusters at 90% utilization.
We began the migration in January 2025. Using ClickHouse’s Merge table feature, we combined the old and new tables, writing all new data to the new partitioned table while the old data aged out.
The mystery: when billing starts to break
Two months later, in late March 2025, our billing team reported that their daily aggregation jobs were slowing down. These jobs are time-critical; if they don’t finish, bills don’t go out. The jobs were getting progressively slower, and we were approaching a deadline.
We investigated, but none of the usual suspects were to blame. I/O was fine. Memory was fine. The metrics for individual queries showed they were not reading more data or more parts than before. Our initial assumption seemed correct, yet the system was grinding to a halt.
It took several days before we even had a theory. Finally, we made a plot of query duration against the total part count in the cluster. The correlation was undeniable.
Average SELECT Query Durations on the Ready Analytics ClickHouse Cluster, showing progressive performance degradation.
Linear Growth in Total Data Part Count per Table Replica, following the new (namespace, day) partitioning scheme.
But why? If we weren’t reading the extra parts, why did their mere existence slow us down?
The investigation: hunting bottlenecks with flame graphs
We turned to ClickHouse’s built-in trace_log to generate flame graphs. This is a built-in table that records traces from the running ClickHouse server. It not only includes traces of what code is being executed, but it associates these with specific users, query IDs and other metadata, meaning you can filter down to quite precise sets of events if necessary. In our case, we wanted to look specifically at leaf SELECT queries. This was easy thanks to the available metadata in this table.
The first CPU-based flame graph quickly confirmed our suspicion: a huge amount of time was being spent in query planning. This is the phase before execution when ClickHouse decides which parts to read.
Flame graph showing that 45% of leaf query CPU time is spent filtering a vector of parts based on the partition ID
The flame graph was clear: 45% of the sampled CPU time was being spent in a single function called filterPartsByPartition.
Our first attempt at a fix was a small patch to this exact code path. The planner evaluates heuristics to prune parts, and we believed they weren’t being evaluated in the optimal order for our table. Our patch changed the order, yielding a small 5% improvement. We were on the right path, but we’d missed the real problem.
We had been generating “CPU” traces, which only sample active threads. We switched to “Real” traces, which sample all threads, including those that are inactive or waiting. The new flame graph was a revelation.
Flame graph showing that more than half of leaf query duration is spent waiting for a mutex that protects the list of active parts
The problem wasn’t CPU-bound work; it was massive lock contention. More than half of our query duration was spent waiting to acquire a single mutex (MergeTreeData) that protects the table’s list of parts. To plan a query, every single thread had to:
Acquire an exclusive lock on this mutex.
Make a complete copy of the list of all parts in the table.
Release the lock.
Filter that list down to the relevant parts.
With tens of thousands of parts and hundreds of concurrent queries, they were all just standing in a single-file line.
The fixes: a trio of patches
This insight helped us plan a series of optimizations to alleviate these hotspots. As with all the patches we make to ClickHouse, we try to make them generic, and eventually get them contributed to the upstream codebase. This makes it easier for us to maintain our fork, and means the community benefits from the changes we make too!
Optimization 1: use a shared lock
The query planner doesn’t modify the parts list; it just reads it. It had no business using an exclusive lock.
The Fix: We modified the code to acquire a shared lock (std::shared_lock) instead. This allowed all query planners to enter the critical section concurrently.
The Result: A massive, immediate drop in query duration. The lock contention vanished.
Immediate Impact of the Shared Lock Optimization (Optimization 1) on Average SELECT Query Durations, demonstrating the resolution of lock contention.
Optimization 2: stop copying the vector
Performance was significantly better, but still not back to baseline. We went back to the trace log and made another ‘Real’ flame graph.
Flame graph showing that we spend a quarter of leaf query duration copying the vector of all parts, and another quarter filtering through it (copying again).
The new flame graph showed the bottleneck had simply moved. Now, time was being spent copying the giant vector of parts, even with the shared lock. Intuitively, copying a vector sounds cheap, but when it contains tens of thousands of elements, and you do it hundreds of times a second, it adds up.
The Fix: We deferred the copy entirely. We created a “shared copy” of the parts list. Read-only operations (like query planning) just read from this copy. Any operation that modifies the set of parts (like a new insert) regenerates the cache. Planners now only copy the filtered list of parts they actually need.
The Result: Another significant performance improvement.
Further Performance Improvement After Rolling Out the Vector Copy Optimization (Optimization 2).
After seeing these massive savings internally, we decided to bring these changes to the community. After some small design iterations with the maintainers at ClickHouse Inc., we got the changes merged underPR #85535. They have been available since ClickHouse version 25.11.
Optimization 3: binary search for parts
We’re still not done. As part counts grow, performance still degrades, just much more slowly. The correlation with part count was still there. Coming back to this after a few months, a new flame graph (looking the same as Figure 3) shows the time is spent in the filtering code path (the one we tried to fix first). This code performs a linear scan over all parts, evaluating predicates against each one. Over a few months, we were back to select durations from before the optimizations.
But we know this list of parts is sorted by the partitioning key. Remember that the first column of the partition key is namespace, which the vast majority of queries filter on, because it identifies the “tenant.” How can we make use of this?
The Fix: We implemented a binary search based on the namespace part of the partition ID. This works because the vector is sorted, so you can filter out a lot of the entries without actually looking at them. This is particularly effective since the namespace is the first part of that sorting key. After this first-pass of binary search, we have a much smaller range of parts we need to examine, and for those we still step through each one, applying the same logic as before to exclude parts based on other conditions.
The Result: After deploying this patch in March 2026, query durations dropped by 50% (see Figure 8). More importantly, this finally breaks correlation of query durations with the number of parts. Unfortunately, this solution doesn’t generalize that well for arbitrary query conditions (e.g. conditions such as namespace in (5,10)). We are looking into more generic approaches like extending the query condition cache to cover part filtering.
Sustained Latency Reduction Following the Implementation of Binary Search for Part Pruning (Optimization 3).
An uneasy truce
These optimizations resolved the immediate crisis with the billing system. But this journey exposed the deep, non-obvious costs of our partitioning choice.
Other problems remain. In this blog post we’ve only described the problems increasing part counts had on our select durations, but it has also caused problems for ZooKeeper, which tracks metadata for all the parts in ClickHouse. Perhaps one day we’ll tell the story of the 100 gigabyte ZooKeeper cluster.
We’ve bought ourselves significant breathing room, but the fundamental question remains: Was this partitioning scheme the right long-term choice? Or will we eventually need to bite the bullet and move to a different architecture? For now, our patches are holding, but the experience was a clear example of how even a well-planned change can fall victim to incorrect assumptions.
When the billing team first reported this problem we had 30,000 parts per replica. The part rate never stopped growing, and a year later we hit 160k parts per replica, but query durations have been stable thanks to the optimizations we made here.
At Cloudflare, we solve complex engineering problems at a massive scale. If the debugging and optimizations we described here sound like the type of challenge you’re looking for, check out some of the open roles we are hiring for.
AI is writing more code than ever. AI-assisted contributions now account for a rapidly growing share of new code across the platform. Agentic coding tools like OpenCode and Claude Code are shipping entire features in minutes.
AI-generated code entering production is only going to accelerate. But the bigger shift isn’t just speed — it’s autonomy.
Today, an AI agent writes code and a human reviews, merges, and deploys it. Tomorrow, the agent does all of that itself. The question becomes: how do you let an agent ship to production without removing every safety net?
Feature flags are the answer. An agent writes a new code path behind a flag and deploys it — the flag is off, so nothing changes for users. The agent then enables the flag for itself or a small test cohort, exercises the feature in production, and observes the results. If metrics look good, it ramps the rollout. If something breaks, it disables the flag. The human doesn’t need to be in the loop for every step — they set the boundaries, and the flag controls the blast radius.
This is the workflow feature flags were always building toward: not just decoupling deployment from release, but decoupling human attention from every stage of the shipping process. The agent moves fast because the flag makes it safe to move fast.
Today, we’re announcing Flagship — Cloudflare’s native feature flag service, built on OpenFeature, the CNCF open standard for feature flag evaluation. It works everywhere — Workers, Node.js, Bun, Deno, and the browser — but it’s fastest on Workers, where flags are evaluated within the Cloudflare network. With the Flagship binding and OpenFeature, integration looks like this:
await OpenFeature.setProviderAndWait(
    new FlagshipServerProvider({ binding: env.FLAGS })
);
Flagship is now available in closed beta.
The problem with feature flags on Workers
Many Cloudflare developers have resorted to the pragmatic workaround: hardcoding flag logic directly into their Workers. And honestly, it works well enough in the beginning. Workers deploy in seconds, so flipping a boolean in code and pushing it to production is fast enough for most situations.
But it doesn’t stay simple. One hardcoded flag becomes ten. Ten becomes fifty, owned by different teams, with no central view of what’s on or off. There’s no audit trail — when something breaks, you’re searching git blame to figure out who toggled what.
Network call to external services
Another common pattern used on workers is to make an HTTP request to an external service in the following manner:
That outbound request sits on the critical path of every single user request. It could add considerable latency depending on how far the user is from the flag service’s region.
This is a strange situation. Your application runs at the edge, milliseconds from the user. But the feature flag check forces it to reach back across the Internet to another API before it can decide what to render.
Why local evaluation doesn’t solve the problem
Some feature flag services offer a “local evaluation” SDK. Instead of calling a remote API on every request, the SDK downloads the full set of flag rules into memory and evaluates them locally. No outbound request per evaluation and the flag decision happens in-process.
On Workers, none of these assumptions hold. There is no long-lived process: a Worker isolate can be created, serve a request, and be evicted between one request and the next. A new invocation could mean re-initializing the SDK from scratch.
On a serverless platform, you need a distribution primitive that’s already at the edge, one where the caching is managed for you, reads are local, and you don’t need a persistent connection to keep things up to date.
Cloudflare KV is a great primitive for this!
How Flagship works
Flagship is built entirely on Cloudflare’s infrastructure — Workers, Durable Objects, and KV. There are no external databases, no third-party services, and no centralized origin servers in the evaluation path.
When you create or update a flag, the control plane writes the change atomically to a Durable Object — a SQLite-backed, globally unique instance that serves as the source of truth for that app’s flag configuration and changelog. Within seconds, the updated flag config is synced to Workers KV, Cloudflare’s globally distributed key-value store, where it’s replicated across Cloudflare’s network.
When a request evaluates a flag, Flagship reads the flag config directly from KV at the edge — the same Cloudflare location already handling the request. The evaluation engine then runs right there in an isolate: it matches the request context against the flag’s targeting rules, resolves the rollout percentage, and returns a variation. Both the data and the logic live at the edge — nothing is sent elsewhere to be evaluated.
Using Flagship: the Worker binding
For teams running Cloudflare Workers, Flagship offers a direct binding that evaluates flags inside the Workers runtime — no HTTP round-trip, no SDK overhead. Add the binding to your wrangler.jsonc and your Worker is connected:
That’s it. Your account ID is inferred from your Cloudflare account, and the app_id ties the binding to a specific Flagship app. In your Worker, you just ask for a flag value:
The binding supports typed accessors for every variation type – getBooleanValue(), getStringValue(), getNumberValue(), getObjectValue() – plus *Details() variants that return the resolved value alongside the matched variant and the reason it was selected. On evaluation errors, the default value is returned gracefully. On type mismatches, the binding throws an exception — that’s a bug in your code, not a transient failure.
The SDK: OpenFeature-native
Most feature flag SDKs come with their own interfaces and evaluation patterns. Over time, those become deeply embedded in your codebase — and switching providers means rewriting every call site.
We didn’t want to build another one of those. Flagship is built on OpenFeature, the CNCF open standard for feature flag evaluation. OpenFeature defines a common interface for flag evaluation across languages and providers — it’s the same relationship that OpenTelemetry has to observability. You write your evaluation code once against the standard, and swap providers by changing a single line of configuration.
If you’re running on Workers with the Flagship binding, you can pass it directly to the OpenFeature provider. The binding already carries your account context, so there’s nothing to configure — authentication is implicit.
Your evaluation code doesn’t change — the OpenFeature interface is identical. But under the hood, Flagship evaluates flags through the binding instead of over HTTP. You get the portability of the standard with the performance of the binding.
A client-side provider is also available for browsers. It pre-fetches the flags you specify, caches them with a configurable TTL, and serves evaluations synchronously from that cache.
What you can do with Flagship
Flagship supports the patterns you’d expect from a feature flag service and the ones that become critical when AI-generated code is landing in production daily.
Flag values can be boolean, strings, numbers, or full JSON objects — useful for configuration blocks, UI theme definitions, or routing users to different API versions without maintaining separate code paths.
Targeting Rules
Each flag can have multiple rules, evaluated in priority order. The first rule that matches wins.
A rule consists of:
Conditions that determine whether the rule applies to a given context
A flag variation to serve when the rule matches
An optional rollout for percentage-based delivery
A priority that determines evaluation order when multiple rules are present (lower number = higher priority)
Nested Logical Conditions
Conditions can be composed using AND/OR logic, nested up to five levels deep. A single rule can express things like:
(plan == “enterprise” AND region == “us” ) OR (user.email.endsWith(“@cloudflare.com”))
= serve (“premium”)
At the top level of a rule, multiple conditions are combined with implicit AND where all conditions must pass for the rule to match. Within each condition, you can nest AND/OR groups for more complex logic.
Flag Rollouts by Percentage
Unlike gradual deployments, which split traffic between different uploaded versions of your Worker, feature flags let you roll out behavior by percentage within a single version that is serving 100% of traffic.
Any rule can include a percentage rollout. Instead of serving a variation to everyone who matches the conditions, you serve it to a percentage of them.
Rollouts use consistent hashing on the specified context attribute. The same attribute value (userId, for example) always hashes to the same bucket, so they won’t flip between variations across requests. You can ramp from 5% to 10% to 50% to 100% of users, so those who were already in the rollout stay in it.
Built for what comes next
AI-generated code entering production is only going to accelerate. Agentic workflows will push it further — agents that autonomously deploy, test, and iterate on code in production. The teams that thrive in this world won’t be the ones shipping the fastest. They’ll be the ones who can ship fast and still maintain control over what their users see, roll back in seconds when something breaks, and gradually expose new code paths with confidence.
That’s what Flagship is built for:
Evaluation across region Earth, cached globally using K/V.
A full audit trail. Every flag change is recorded with field-level diffs, so you know who changed what and when.
Dashboard integration. Anyone on the team can toggle a flag or adjust a rollout without touching code.
OpenFeature compatibility. Adopt Flagship without rewriting your evaluation code. Leave without rewriting it either.
Get started with Flagship
Starting today, Flagship is in private beta. You can request for access here. We’ll share more details on pricing as we approach general availability.
Install the SDK: npm i @cloudflare/flagship; or use the Worker binding directly in your Worker
Read the documentation for integration guides and API reference
Check out the source code for examples and to contribute
If you’re currently hardcoding flags in your Workers, or evaluating flags through an external service that adds latency to every request, give Flagship a try. We’d love to hear what you build.
When it comes to the Internet, performance is everything. Every millisecond shaved off a connection is a better experience for the real people using the applications and websites you build. That’s why, at Cloudflare, we measure our performance constantly and share updates on a regular basis.
In our last performance post, published during Birthday Week 2025, we shared that Cloudflare was the fastest network in 40% of the largest 1,000 networks in the world. At the time, we noted a nuanced reading of that figure; we were competitive in many more networks, and the gaps were often notably small. But even so, we were not satisfied with 40%. By December 2025 (our most recent available analysis), we had become the fastest provider in 60% of the top networks. Here’s how we got there, and what it means.
How do we measure and compare network performance?
Before diving into the results, let’s review how we collect the data. We start with the 1,000 largest networks in the world by estimated population, using APNIC’s data as our source. These networks represent real users in nearly every geography, giving us a broad and meaningful picture of how Internet users experience the web.
To measure performance, we use TCP connection time, which is the time it takes for an end user’s device to complete a TCP handshake with the endpoint they’re trying to reach. We chose this metric because it most closely approximates what users actually perceive as “Internet speed.” It’s not so abstract that it ignores real-world constraints like congestion and distance, but it’s precise enough to give us actionable data. (We’ve previously written about why we favor this metric over alternatives.)
We calculate our rankings using the trimean of TCP connection times. The trimean is a weighted average of three values: the first quartile (25th percentile), the median (50th percentile), and the third quartile (75th percentile). This approach smooths out noise and outliers, giving us a cleaner signal about the typical user experience rather than an extreme case that might skew the picture.
To capture this data, we rely on Real User Measurements (RUM). When users encounter a Cloudflare-branded error page, a small speed test runs silently in the background. The browser retrieves small files from multiple providers including Cloudflare, Amazon CloudFront, Google, Fastly, and Akamai and records how long each exchange takes. This gives us performance data directly from the user’s browser, in their real-world network conditions. It’s the difference between testing a car’s top speed on a track versus watching how people actually drive on the highway.
How did we improve?
Historically we have shared how we’ve created new Cloudflare points of presence and reduced our end latency by simply getting more hardware closer to our users. Most recently, we deployed new locations in Constantine, Algeria; Malang, Indonesia; and Wroclaw, Poland. When we deployed our location in Wroclaw, our free users went from an average of 19ms round-trip time (RTT) to an average of 12ms round trip time (RTT), a 40% improvement. In Malang, Enterprise traffic went from a 39ms average RTT to a 37ms average RTT, a 5% improvement. Seeing our customers’ experience improve, even if only by a couple of milliseconds, is great. But adding new locations alone doesn’t fully explain how we went from being #1 in 40% of networks to #1 in 60% of networks.
The answer there has to do with improving how our network handles connections in software. By leveraging protocols like HTTP/3 and changing how we manage congestion windows, we can reduce processing time by milliseconds in code, in addition to the improvements on the wire. By improving CPU usage and memory usage in our software that handles fundamental actions like establishing connections, SSL/TLS termination, traffic management, and the core proxy that all requests flow through, we can make that software more efficient in its usage of resources across our global fleet of hardware. These ongoing efficiency gains result in better performance for you and your customers.
Think of incoming connections to Cloudflare like toll booths on a highway. Lines can build up at toll booths if there aren’t enough toll booths, or if the booths themselves aren’t efficient at processing cars going through them. We’ve been constantly working to improve not only how our toll booths process incoming cars (the software improvements in connection handling), but also at improving how we send cars between available booths so that we can keep lines short and latency low.
How do the results look today?
As we noted above, by December, Cloudflare had become the fastest provider in 60% of the top networks, up from 40% when we last reported. Since Birthday Week in September 2025 we have steadily increased the networks where we are the fastest. Let’s break down the impact.
This means that between September and December, we became the fastest in 40 additional countries and in 261 additional networks. We saw the biggest increase in the United States, where we are the fastest in 54 more ASNs.
On average throughout December, we were 6ms faster than the next-fastest provider. As shown above, the line representing Cloudflare’s latency, or connection time, is consistently lower throughout December than the next fastest provider.
A faster Internet is a better Internet
Every percentage point in our network ranking represents real users who are able to connect to their website or application that much faster because of Cloudflare. But we also know that 60% isn’t the ceiling. There are still networks where we’re number two, sometimes by the smallest of margins. We see those gaps clearly, and we’re working on them. We’re committed to being the fastest provider across every network in the world.
Follow our blog for more performance updates as we continue to make the Internet faster.
Validating Kafka configurations before production deployment can be challenging. In this post, we introduce the workload simulation workbench for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express Broker. The simulation workbench is a tool that you can use to safely validate your streaming configurations through realistic testing scenarios.
Solution overview
Varying message sizes, partition strategies, throughput requirements, and scaling patterns make it challenging for you to predict how your Apache Kafka configurations will perform in production. The traditional approaches to test these variables create significant barriers: ad-hoc testing lacks consistency, manual set up of temporary clusters is time-consuming and error-prone, production-like environments require dedicated infrastructure teams, and team training often happens in isolation without realistic scenarios. You need a structured way to test and validate these configurations safely before deployment. The workload simulation workbench for MSK Express Broker addresses these challenges by providing a configurable, infrastructure as code (IaC) solution using AWS Cloud Development Kit (AWS CDK) deployments for realistic Apache Kafka testing. The workbench supports configurable workload scenarios, and real-time performance insights.
Express brokers for MSK Provisioned make managing Apache Kafka more streamlined, more cost-effective to run at scale, and more elastic with the low latency that you expect. Each broker node can provide up to 3x more throughput per broker, scale up to 20x faster, and recover 90% quicker compared to standard Apache Kafka brokers. The workload simulation workbench for Amazon MSK Express broker facilitates systematic experimentation with consistent, repeatable results. You can use the workbench for multiple use cases like production capacity planning, progressive training to prepare developers for Apache Kafka operations with increasing complexity, and architecture validation to prove streaming designs and compare different approaches before making production commitments.
Architecture overview
The workbench creates an isolated Apache Kafka testing environment in your AWS account. It deploys a private subnet where consumer and producer applications run as containers, connects to a private MSK Express broker and monitors for performance metrics and visibility. This architecture mirrors the production deployment pattern for experimentation. The following image describes this architecture using AWS services.
This architecture is deployed using the following AWS services:
Amazon Elastic Container Service (Amazon ECS)generate configurable workloads with Java-based producers and consumers, simulating various real-world scenarios through different message sizes and throughput patterns.
Dynamic Amazon CloudWatch Dashboards automatically adapt to your configuration, displaying real-time throughput, latency, and resource utilization across different test scenarios.
The workbench provides different configuration options for your Apache Kafka testing environment, so you can customize instance types, broker count, topic distribution, message characteristics, and ingress rate. You can adjust the number of topics, partitions per topic, sender and receiver service instances, and message sizes to match your testing needs. These flexible configurations support two distinct testing approaches to validate different aspects of your Kafka deployment:
Test different workload patterns against the same MSK Express cluster configuration. This is useful for comparing partition strategies, message sizes, and load patterns.
Approach 2: Infrastructure rightsizing (redeploy and compare)
Test different MSK Express cluster configurations by redeploying the workbench with different broker settings while keeping the same workload. This is recommended for rightsizing experiments and understanding the impact of vertical compared to horizontal scaling.
// Baseline: Deploy and test
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1, instanceType: 'express.m7g.large',};

// Vertical scaling: Redeploy with larger instances
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1,
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Horizontal scaling: Redeploy with more brokers
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // More brokers
instanceType: 'express.m7g.large',};
Each redeployment uses the same workload configuration, so you can isolate the impact of infrastructure changes on performance.
Workload testing scenarios (single deployment)
These scenarios test different workload patterns against the same MSK Express cluster:
Partition strategy impact testing
Scenario: You are debating the usage of fewer topics with many partitions compared to many topics with fewer partitions for your microservices architecture. You want to understand how partition count affects throughput and consumer group coordination before making this architectural decision.
Scenario: Your application handles different types of events – small IoT sensor readings (256 bytes), medium user activity events (1 KB), and large document processing events (8KB). You must understand how message size impacts your overall system performance and if you should separate these into different topics or handle them together.
Scenario: You expect traffic to vary significantly throughout the day, with peak loads requiring 10× more processing capacity than off-peak hours. You want to validate how your Apache Kafka topics and partitions handle different load levels and understand the performance characteristics before production deployment.
Infrastructure rightsizing experiments (redeploy and compare)
These scenarios help you understand the impact of different MSK Express cluster configurations by redeploying the workbench with different broker settings:
MSK broker rightsizing analysis
Scenario: You deploy a cluster with basic configuration and put load on it to establish baseline performance. Then you want to experiment with different broker configurations to see the effect of vertical scaling (larger instances) and horizontal scaling (more brokers) to find the right cost-performance balance for your production deployment.
// Redeploy: Test vertical scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // Same broker count
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Keep same workload configuration to compare results
Step 3: Redeploy with horizontal scaling
// Redeploy: Test horizontal scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // 6 total brokers (2 per AZ)
instanceType: 'express.m7g.large', // Back to original size
};

// Keep same workload configuration to compare results
This rightsizing approach helps you understand how broker configuration changes affect the same workload, so you can improve both performance and cost for your specific requirements.
Performance insights
The workbench provides detailed insights into your Apache Kafka configurations through monitoring and analytics, creating a CloudWatch dashboard that adapts to your configuration. The dashboard starts with a configuration summary showing your MSK Express cluster details and workbench service configurations, helping you to understand what you’re testing. The following image shows the dashboard configuration summary:
The second section of dashboard shows real-time MSK Express cluster metrics including:
Broker performance: CPU utilization and memory usage across brokers in your cluster
Network activity: Monitor bytes in/out and packet counts per broker to understand network utilization patterns
Connection monitoring: Displays active connections and connection patterns to help identify potential bottlenecks
Resource utilization: Broker-level resource tracking provides insights into overall cluster health
The following image shows the MSK cluster monitoring dashboard:
The third section of the dashboard shows the Intelligent Rebalancing and Cluster Capacity insights showing:
Intelligent rebalancing: in progress: Shows whether a rebalancing operation is currently in progress or has occurred in the past. A value of 1 indicates that rebalancing is actively running, while 0 means that the cluster is in a steady state.
Cluster under-provisioned: Indicates whether the cluster has insufficient broker capacity to perform partition rebalancing. A value of 1 means that the cluster is under-provisioned and Intelligent Rebalancing can’t redistribute partitions until more brokers are added or the instance type is upgraded.
Global partition count: Displays the total number of unique partitions across all topics in the cluster, excluding replicas. Use this to track partition growth over time and validate your deployment configuration.
Leader count per broker: Shows the number of leader partitions assigned to each broker. An uneven distribution indicates partition leadership skew, which can lead to hotspots where certain brokers handle disproportionate read/write traffic.
Partition count per broker: Shows the total number of partition replicas hosted on each broker. This metric includes both leader and follower replicas and is key to identifying replica distribution imbalances across the cluster.
The following image shows the Intelligent Rebalancing and Cluster Capacity section of the dashboard:
The fourth section of the dashboard shows the application-level insights showing:
System throughput: Displays the total number of messages per second across services, giving you a complete view of system performance
Service comparisons: Performs side-by-side performance analysis of different configurations to understand which approaches fit
Individual service performance: Each configured service has dedicated throughput tracking widgets for detailed analysis
Latency analysis: The end-to-end message delivery times and latency comparisons across different service configurations
Message size impact: Performance analysis across different payload sizes helps you understand how message size affects overall system behavior
The following image shows the application performance metrics section of the dashboard:
Getting started
This section walks you through setting up and deploying the workbench in your AWS environment. You will configure the necessary prerequisites, deploy the infrastructure using AWS CDK, and customize your first test.
Prerequisites
You can deploy the solution from the GitHub Repo. You can clone it and run it on your AWS environment. To deploy the artifacts, you will require:
AWS account with administrative credentials configured for creating AWS resources.
Node.js version 20.9 or higher is required, with version 22+ recommended.
Docker engine must be installed and running locally as the CDK builds container images during deployment. Docker daemon should be running and accessible to CDK for building the workbench application containers.
Deployment
# Clone the workbench repository
git clone https://github.com/aws-samples/sample-simulation-workbench-for-msk-express-brokers.git

# Install dependencies and build
npm install
npm run build

# Bootstrap CDK (first time only per account/region)
cd cdk
npx cdk bootstrap

# Synthesize CloudFormation template (optional verification step)
npx cdk synth

# Deploy to AWS (creates infrastructure and builds containers)
npx cdk deploy
After deployment is completed, you will receive a CloudWatch dashboard URL to monitor the workbench performance in real-time.You can also deploy multiple isolated instances of the workbench in the same AWS account for different teams, environments, or testing scenarios. Each instance operates independently with its own MSK cluster, ECS services, and CloudWatch dashboards.To deploy additional instances, modify the Environment Configuration in cdk/lib/config.ts:
Each combination of AppPrefix and EnvPrefix creates completely isolated AWS resources so that multiple teams or environments can use the workbench simultaneously without conflicts.
Customizing your first test
You can edit the configuration file located at folder “cdk/lib/config-types.ts” to define your testing scenarios and run the deployment. It is preconfigured with the following configuration:
Following a structured approach to benchmarking ensures that your results are reliable and actionable. These best practices will help you isolate performance variables and build a clear understanding of how each configuration change affects your system’s behavior. Begin with single-service configurations to establish baseline performance:
This approach helps you understand the impact of specific configuration changes.
Important considerations and limitations
Before relying on workbench results for production decisions, it is important to understand the tool’s intended scope and boundaries. The following considerations will help you set appropriate expectations and make the most effective use of the workbench in your planning process.
Performance testing disclaimer
The workbench is designed as an educational and sizing estimation tool to help teams prepare for MSK Express production deployments. While it provides valuable insights into performance characteristics:
Results can vary based on your specific use cases, network conditions, and configurations
Use workbench results as guidance for initial sizing and planning
Conduct comprehensive performance validation with your actual workloads in production-like environments before final deployment
Recommended usage approach
Production readiness training – Use the workbench to prepare teams for MSK Express capabilities and operations.
Architecture validation – Test streaming architectures and performance expectations using MSK Express enhanced performance characteristics.
Capacity planning – Use MSK Express streamlined sizing approach (throughput-based rather than storage-based) for initial estimates.
Team preparation – Build confidence and expertise with production Apache Kafka implementations using MSK Express.
Conclusion
In this post, we showed how the workload simulation workbench for Amazon MSK Express Broker supports learning and preparation for production deployments through configurable, hands-on testing and experiments. You can use the workbench to validate configurations, build expertise, and improve performance before production deployment. If you’re preparing for your first Apache Kafka deployment, training a team, or improving existing architectures, the workbench provides practical experience and insights needed for success. Refer to Amazon MSK documentation – Complete MSK Express documentation, best practices, and sizing guidance for more information.
Two years ago, Cloudflare deployed our 12th Generation server fleet, based on AMD EPYC™ Genoa-X processors with their massive 3D V-Cache. That cache-heavy architecture was a perfect match for our request handling layer, FL1 at the time. But as we evaluated next-generation hardware, we faced a dilemma — the CPUs offering the biggest throughput gains came with a significant cache reduction. Our legacy software stack wasn’t optimized for this, and the potential throughput benefits were being capped by increasing latency.
This blog describes how the FL2 transition, our Rust-based rewrite of Cloudflare’s core request handling layer, allowed us to prove Gen 13’s full potential and unlock performance gains that would have been impossible on our previous stack. FL2 removes the dependency on the larger cache, allowing for performance to scale with cores while maintaining our SLAs. Today, we are proud to announce the launch of Cloudflare’s Gen 13 based on AMD EPYC™ 5th Gen Turin-based servers running FL2, effectively capturing and scaling performance at the edge.
What AMD EPYCTurin brings to the table
AMD’s EPYC™ 5th Generation Turin-based processors deliver more than just a core count increase. The architecture delivers improvements across multiple dimensions of what Cloudflare servers require.
2x core count: up to 192 cores versus Gen 12’s 96 cores, with SMT providing 384 threads
Improved IPC: Zen 5’s architectural improvements deliver better instructions-per-cycle compared to Zen 4
Better power efficiency: Despite the higher core count, Turin consumes up to 32% fewer watts per core compared to Genoa-X
DDR5-6400 support: Higher memory bandwidth to feed all those cores
However, Turin’s high density OPNs make a deliberate tradeoff: prioritizing throughput over per core cache. Our analysis across the Turin stack highlighted this shift. For example, comparing the highest density Turin OPN to our Gen 12 Genoa-X processors reveals that Turin’s 192 cores share 384MB of L3 cache. This leaves each core with access to just 2MB, one-sixth of Gen 12’s allocation. For any workload that relies heavily on cache locality, which ours did, this reduction posed a serious challenge.
Generation
Processor
Cores/Threads
L3 Cache/Core
Gen 12
AMD Genoa-X 9684X
96C/192T
12MB (3D V-Cache)
Gen 13 Option 1
AMD Turin 9755
128C/256T
4MB
Gen 13 Option 2
AMD Turin 9845
160C/320T
2MB
Gen 13 Option 3
AMD Turin 9965
192C/384T
2MB
Diagnosing the problem with performance counters
For our FL1 request handling layer, NGINX- and LuaJIT-based code, this cache reduction presented a significant challenge. But we didn’t just assume it would be a problem; we measured it.
During the CPU evaluation phase for Gen 13, we collected CPU performance counters and profiling data to identify exactly what was happening under the hood using AMD uProf tool. The data showed:
L3 cache miss rates increased dramatically compared to Gen 12’s server equipped with 3D V-cache processors
Memory fetch latency dominated request processing time as data that previously stayed in L3 now required trips to DRAM
The latency penalty scaled with utilization as we pushed CPU usage higher, and cache contention worsened
L3 cache hits complete in roughly 50 cycles; L3 cache misses requiring DRAM access take 350+ cycles, an order of magnitude difference. With 6x less cache per core, FL1 on Gen 13 was hitting memory far more often, incurring latency penalties.
The tradeoff: latency vs. throughput
Our initial tests running FL1 on Gen 13 confirmed what the performance counters had already suggested. While the Turin processor could achieve higher throughput, it came at a steep latency cost.
Metric
Gen 12 (FL1)
Gen 13 – AMD Turin 9755 (FL1)
Gen 13 – AMD Turin 9845 (FL1)
Gen 13 – AMD Turin 9965 (FL1)
Delta
Core count
baseline
+33%
+67%
+100%
FL throughput
baseline
+10%
+31%
+62%
Improvement
Latency at low to moderate CPU utilization
baseline
+10%
+30%
+30%
Regression
Latency at high CPU utilization
baseline
> 20%
> 50%
> 50%
Unacceptable
The Gen 13 evaluation server with AMD Turin 9965 that generated 60% throughput gain was compelling, and the performance uplift provided the most improvement to Cloudflare’s total cost of ownership (TCO).
But a more than 50% latency penalty is not acceptable. The increase in request processing latency would directly impact customer experience. We faced a familiar infrastructure question: do we accept a solution with no TCO benefit, accept the increased latency tradeoff, or find a way to boost efficiency without adding latency?
Incremental gains with performance tuning
To find a path to an optimal outcome, we collaborated with AMD to analyze the Turin 9965 data and run targeted optimization experiments. We systematically tested multiple configurations:
Hardware Tuning: Adjusting hardware prefetchers and Data Fabric (DF) Probe Filters, which showed only marginal gains
Scaling Workers: Launching more FL1 workers, which improved throughput but cannibalized resources from other production services
CPU Pinning & Isolation: Adjusting workload isolation configurations to find optimal mix, with limited success
The configuration that ultimately provided the most value was AMD’s Platform Quality of Service (PQOS). PQOS extensions enable fine-grained regulation of shared resources like cache and memory bandwidth. Since Turin processors consist of one I/O Die and up to 12 Core Complex Dies (CCDs), each sharing an L3 cache across up to 16 cores, we put this to the test. Here is how the different experimental configurations performed.
First, we used PQOS to allocate a dedicated L3 cache share within a single CCD for FL1, the gains were minimal. However, when we scaled the concept to the socket level, dedicating an entire CCD strictly to FL1, we saw meaningful throughput gains while keeping latency acceptable.
Configuration
Description
Illustration
Performance gain
NUMA-aware core affinity (equivalent to PQOS at socket level)
6 out of 12 CCD (aligned with NUMA domain) run FL.
32MB L3 cache in each CCD shared among all cores.
>15% incremental
throughput gain
PQOS config 1
1 of 2 vCPU on each physical core in each CCD runs FL.
FL gets 75% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
Other services show minor signs of degradation
PQOS config 2
1 of 2 vCPU in each physical core in each CCD runs FL.
FL gets 50% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
PQOS config 3
2 vCPU on 50% of the physical core in each CCD runs FL.
FL gets 50% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
The opportunity: FL2 was already in progress
Hardware tuning and resource configuration provided modest gains, but to truly unlock the performance potential of the Gen 13 architecture, we knew we would have to rewrite our software stack to fundamentally change how it utilized system resources.
Fortunately, we weren’t starting from scratch. As we announced during Birthday Week 2025, we had already been rebuilding FL1 from the ground up. FL2 is a complete rewrite of our request handling layer in Rust, built on our Pingora and Oxy frameworks, replacing 15 years of NGINX and LuaJIT code.
The FL2 project wasn’t initiated to solve the Gen 13 cache problem — it was driven by the need for better security (Rust’s memory safety), faster development velocity (strict module system), and improved performance across the board (less CPU, less memory, modular execution).
FL2’s cleaner architecture, with better memory access patterns and less dynamic allocation, might not depend on massive L3 caches the way FL1 did. This gave us an opportunity to use the FL2 transition to prove whether Gen 13’s throughput gains could be realized without the latency penalty.
Proving it out: FL2 on Gen 13
As the FL2 rollout progressed, production metrics from our Gen 13 servers validated what we had hypothesized.
Metric
Gen 13 AMD Turin 9965 (FL1)
Gen 13 AMD Turin 9965 (FL2)
FL requests per CPU%
baseline
50% higher
Latency vs Gen 12
baseline
70% lower
Throughput vs Gen 12
62% higher
100% higher
The out-of-the-box efficiency gains on our new FL2 stack were substantial, even before any system optimizations. FL2 slashed the latency penalty by 70%, allowing us to push Gen 13 to higher CPU utilization while strictly meeting our latency SLAs. Under FL1, this would have been impossible.
By effectively eliminating the cache bottleneck, FL2 enables our throughput to scale linearly with core count. The impact is undeniable on the high-density AMD Turin 9965: we achieved a 2x performance gain, unlocking the true potential of the hardware. With further system tuning, we expect to squeeze even more power out of our Gen 13 fleet.
Generational improvement with Gen 13
With FL2 unlocking the immense throughput of the high-core-count AMD Turin 9965, we have officially selected these processors for our Gen 13 deployment. Hardware qualification is complete, and Gen 13 servers are now shipping at scale to support our global rollout.
Performance improvements
Gen 12
Gen 13
Processor
AMD EPYC™ 4th Gen Genoa-X 9684X
AMD EPYC™ 5th Gen Turin 9965
Core count
96C/192T
192C/384T
FL throughput
baseline
Up to +100%
Performance per watt
baseline
Up to +50%
Gen 13 business impact
Up to 2x throughput vs Gen 12 for uncompromising customer experience: By doubling our throughput capacity while staying within our latency SLAs, we guarantee our applications remain fast and responsive, and able to absorb massive traffic spikes.
50% better performance/watt vs Gen 12 for sustainable scaling: This gain in power efficiency not only reduces data center expansion costs, but allows us to process growing traffic with a vastly lower carbon footprint per request.
60% higher rack throughput vs Gen 12 for global edge upgrades: Because we achieved this throughput density while keeping the rack power budget constant, we can seamlessly deploy this next generation compute anywhere in the world across our global edge network, delivering top tier performance exactly where our customers want it.
Gen 13 + FL2: ready for the edge
Our legacy request serving layer FL1 hit a cache contention wall on Gen 13, forcing an unacceptable tradeoff between throughput and latency. Instead of compromising, we built FL2.
Designed with a vastly leaner memory access pattern, FL2 removes our dependency on massive L3 caches and allows linear scaling with core count. Running on the Gen 13 AMD Turin platform, FL2 unlocks 2x the throughput and a 50% boost in power efficiency all while keeping latency within our SLAs. This leap forward is a great reminder of the importance of hardware-software co-design. Unconstrained by cache limits, Gen 13 servers are now ready to be deployed to serve millions of requests across Cloudflare’s global network.
If you’re excited about working on infrastructure at global scale, we’re hiring.
Ranker is one of the largest and most complex services at Netflix. Among many things, it powers the personalized rows you see on the Netflix homepage, and runs at an enormous scale. When we looked at CPU profiles for this service, one feature kept standing out: video serendipity scoring — the logic that answers a simple question:
“How different is this new title from what you’ve been watching so far?”
This single feature was consuming about 7.5% of total CPU on each node running the service. What started as a simple idea — “just batch the video scoring feature” — turned into a deeper optimization journey. Along the way we introduced batching, re-architected memory layout and tried various libraries to handle the scoring kernels.
Read on to learn how we achieved the same serendipity scores, but at a meaningfully lower CPU per request, resulting in a reduced cluster footprint.
Problem: The Hotspot in Ranker
At a high level, serendipity scoring works like this: A candidate title and each item in a member’s viewing history are represented as embeddings in a vector space. For each candidate, we compute its similarity against the history embeddings, find the maximum similarity, and convert that into a “novelty” score. That score becomes an input feature to the downstream recommendation logic.
The original implementation was straightforward but expensive. For each candidate we fetch its embedding, loop over the history to compute cosine similarity one pair at a time and track the maximum similarity score. Although it is easy to reason about, at Ranker’s scale, this results in significant sequential work, repeated embedding lookups, scattered memory access, and poor cache locality. Profiling confirmed this.
Flamegraph showing inefficient scoring
A flamegraph made it clear: One of the top hotspots in the service was Java dot products inside the serendipity encoder. Algorithmically, the hotspot was a nested loop structure of M candidates × N history items where each pair generates its own cosine similarity i.e. O(M×N) separate dot product operations.
Solution
The Original Implementation: Single video cosine loop
In simplified form the code looked like this:
for (Video candidate : candidates) { Vector c = embedding(candidate); // D-dimensional double maxSim = -1.0;
for (Video h : history) { Vector v = embedding(h); // D-dimensional double sim = cosine(c, v); // dot(c, v) / (||c|| * ||v||) maxSim = Math.max(maxSim, sim); }
The nested for loop with O(M×N) separate dot products brought upon its own overheads. One interesting detail we learned by instrumenting traffic shapes: most requests (about 98%) were single-video, but the remaining 2% were large batch requests. Because those batches were so large, the total volume of videos processed ended up being roughly 50:50 between single and batch jobs. This made batching worth pursuing even if it didn’t help the median request.
Step 1 : Batching, from Nested Loops to Matrix Multiply
The first idea was to stop thinking in terms of “many small dot products” and instead treat the work as a matrix operation. i.e. For batch candidates, implement a data layout to parallelize the math in a single operation i.e. matrix multiply. If D is the embedding dimension:
Pack all candidate embeddings into a matrix A of shape M x D
Pack all history embeddings into a matrix B of shape N x D
Normalize all rows to unit length.
Compute: cosine similarities as [ C = A x B^T ]; where C is an M x N matrix of cosine similarities.
In pseudo‑code:
// Build matrices
double[][] A = new double[M][D]; // candidates
double[][] B = new double[N][D]; // history

for (int i = 0; i < M; i++) {
  A[i] = embedding(candidates[i]).toArray();
}
for (int j = 0; j < N; j++) {
  B[j] = embedding(history[j]).toArray();
}

// Normalize rows to unit vectors
normalizeRows(A);
normalizeRows(B);

// Compute C = A * B^T
double[][] C = matmul(A, B);
C[i][j] = cosine(candidates[i], history[j])

// Derive serendipity
for (int i = 0; i < M; i++) {
  double maxSim = max(C[i][0..N-1]);
  double serendipity = 1.0 - maxSim;
  emitFeature(candidates[i], serendipity);
}
This turns M×N separate dot products into a single matrix multiply, which is exactly what CPUs and optimized kernels are built for. We integrated this into the existing framework by supporting both, encode()for single videos and batchEncode() for batches, while maintaining backward compatibility. At this point it seemed like we were “done”, but we weren't.
Step 2: When Batching Isn’t Enough
Once we had a batched implementation, we ran canaries and saw something surprising: about a 5% performance regression. The algorithm wasn’t the issue — turning M×N separate dot products into a matrix multiplication is mathematically sound. The problem was the overhead we introduced in the first implementation.
Our initial version built double[][] matrices for candidates, history, and results on every batch. Those large, short-lived allocations created GC pressure, and the double[][] layout itself is non-contiguous in memory, which meant extra pointer chasing and worse cache behavior.
On top of that, the first-cut Java matrix multiply was a straightforward scalar implementation, so it couldn’t take advantage of SIMD. In other words, we paid the cost of batching without getting the compute efficiency we were aiming for.
The lesson was immediate: algorithmic improvements don’t matter if the implementation details—memory layout, allocation strategy, and the compute kernel—work against you. That set up the next step for making the data layout cache-friendly and eliminating per-batch allocations before revisiting the matrix multiply kernel.
Step 3: Flat Buffers & ThreadLocal Reuse
We reworked the data layout to be cache-friendly and allocation-light. Instead of double[m][n], we moved to flat double[] buffers in row-major order. That gave us contiguous memory and predictable access patterns. Then we introduced a ThreadLocal<BufferHolder> that owns reusable buffers for candidates, history, and any other scratch space. Buffers grow as needed but never shrink, which avoids per-request allocation while keeping each thread isolated (no contention). A simplified sketch:
class BufferHolder {
  double[] candidatesFlat = new double[0];
  double[] historyFlat = new double[0];

  double[] getCandidatesFlat(int required) {
    if (candidatesFlat.length < required) {
      candidatesFlat = new double[required];
    }
    return candidatesFlat;
  }

  double[] getHistoryFlat(int required) {
    if (historyFlat.length < required) {
      historyFlat = new double[required];
    }
    return historyFlat;
  }
}

private static final ThreadLocal<BufferHolder> threadBuffers =
    ThreadLocal.withInitial(BufferHolder::new);
This change alone made the batched path far more predictable: fewer allocations, less GC pressure, and better cache locality.
Now the remaining question was the one we originally thought we were answering: what’s the best way to do the matrix multiply?
Step 4: BLAS: Great in Tests, Not in Production
The obvious next step was BLAS (Basic Linear Algebra Subprograms). In isolation, microbenchmarks looked promising. But once integrated into the real batch scoring path, the gains didn’t materialize. A few things were working against us:
The default netlib-java path was using F2J (Fortran-to-Java) BLAS rather than a truly native implementation.
Even with native BLAS, we paid overhead for setup and JNI transitions.
Java’s row-major layout doesn’t match the column-major expectations of many BLAS routines, which can introduce conversion and temporary buffers.
Those extra allocations and copies mattered in the full pipeline, especially alongside TensorFlow embedding work.
BLAS was still a useful experiment — it clarified where time was being spent, but it wasn’t the drop-in win we wanted. What we needed was something that stayed pure Java, fit our flat-buffer architecture, and could still exploit SIMD.
Step 5: JDK Vector API to the rescue
A Short Note on the JDK Vector API: The JDK Vector API is an incubating feature that provides a portable way to express data-parallel operations in Java — think “SIMD without intrinsics”. You write in terms of vectors and lanes, and the JIT maps those operations to the best SIMD instructions available on the host CPU (SSE/AVX2/AVX-512), with a scalar fallback when needed. More crucially for us, it’s pure Java: no native dependencies, no JNI transitions, and a development model that looks like normal Java code rather than platform-specific assembly or intrinsics.
This was a particularly good match for our workload because we had already moved embeddings into flat, contiguous double[] buffers, and the hot loop was dominated by large numbers of dot products. The final step was to replace BLAS with a pure-Java SIMD implementation using the JDK Vector API. By this point we already had the right shape for high performance — batching, flat buffers, and ThreadLocal reuse. So the remaining work was to swap out the compute kernel without introducing JNI overhead or platform-specific code. We did that behind a small factory. At class load time, MatMulFactory selects the best available implementation:
If jdk.incubator.vector is available, use a Vector API implementation.
Otherwise, fall back to a scalar implementation with a highly optimized loop-unrolled dot product (implemented by my colleague Patrick Strawderman, inspired by patterns used in Lucene)
In the Vector API implementation, the inner loop computes a dot product by accumulating a * b into a vector accumulator using fma() (fused multiply-add). DoubleVector.SPECIES_PREFERRED lets the runtime pick an appropriate lane width for the machine. Here’s a simplified sketch of the inner loop:
// Vector API path (simplified)
for (int i = 0; i < M; i++) {
  for (int j = 0; j < N; j++) {

  DoubleVector acc = DoubleVector.zero(SPECIES);
    int k = 0;
    // SPECIES.length() (e.g. often 4 doubles on AVX2 and 8 doubles on AVX-512).
    for (; k + SPECIES.length() <= D; k += SPECIES.length()) {
      DoubleVector a = DoubleVector.fromArray(SPECIES, candidatesFlat, i*D + k);
      DoubleVector b = DoubleVector.fromArray(SPECIES, historyFlat,   j*D + k);
      acc = a.fma(b, acc);  // fused multiply-add
    }
    double dot = acc.reduceLanes(VectorOperators.ADD);
    // handle tail k..D-1
    similaritiesFlat[i*N + j] = dot;
  }
}
Figure below shows how the Vector API utilizes SIMD hardware to process multiple doubles per instruction (e.g., 4 lanes on AVX2 and 8 lanes on AVX‑512). What used to be many scalar multiply-adds becomes a smaller number of vector fma() operations plus a reduction—same algorithm, much better use of the CPU’s vector units.
Vectorization with SIMD
Fallbacks & Safety: When the Vector API Isn’t Available
Because the Vector API is still incubating, it requires a runtime flag: –add-modules=jdk.incubator.vector We didn’t want correctness or availability to depend on that flag. So we designed the fallback behavior explicitly: At startup, we detect Vector API support and use the SIMD batched matmul when available; otherwise we fall back to an optimized scalar path, with single-video requests continuing to use the per-item implementation.
That gives us a clean operational story: services can opt in to the Vector API for maximum performance, but the system remains safe and predictable without it.
Results in Production:
With the full design in place with batching, flat buffers, ThreadLocal reuse, and the Vector API, we ran canaries that run production traffic. We observed a ~7% drop in CPU utilization and ~12% drop in average latency. To normalize across any small throughput differences, we also tracked CPU/RPS (CPU consumed per request-per-second). That metric improved by roughly 10%, meaning we could handle the same traffic with about 10% less CPU, and we saw similar numbers hold after full production rollout.
CPU/RPS on Ranker
At the function operator level, we saw the CPU drop from the initial 7.5% to a merely ~1% with the optimization in place. At the assembly level, the shift was clear: from loop-unrolled scalar dot products to a vectorized matrix multiply on AVX-512 hardware.
Assembly snippet from batchEncode
Closing Thoughts
This optimization ended up being less about finding the “fastest library” and more about getting the fundamentals right: choosing the right computation shape, keeping data layout cache-friendly, and avoiding overheads that can erase theoretical wins. Once those pieces were in place, the JDK Vector API was a great fit, as it let us express SIMD-style math in pure Java, without JNI, while still keeping a safe fallback path. Another bonus was the low developer overhead: compared to lower-level approaches, the Vector API let us replace a much larger, more complex implementation with a relatively small amount of readable Java code, which made it easier to review, maintain, and iterate on.
Have you tried the Vector API in a real service yet? I’d love to hear what workloads it helped (or didn’t), and what you learned about benchmarking and rollout in production.
Imagine this — you click play on Netflix on a Friday night and behind the scenes hundreds of containers spring to action in a few seconds to answer your call. At Netflix, scaling containers efficiently is critical to delivering a seamless streaming experience to millions of members worldwide. To keep up with responsiveness at this scale, we modernized our container runtime, only to hit a surprising bottleneck: the CPU architecture itself.
Let us walk you through the story of how we diagnosed the problem and what we learned about scaling containers at the hardware level.
The Problem
When application demand requires that we scale up our servers, we get a new instance from AWS. To use this new capacity efficiently, pods are assigned to the node until its resources are considered fully allocated. A node can go from no applications running to being maxed out within moments of being ready to receive these applications.
As we migrated more and more from our old container platform to our new container platform, we started seeing some concerning trends. Some nodes were stalling for long periods of time, with a simple health check timing out after 30 seconds. An initial investigation showed that the mount table length was increasing dramatically in these situations, and reading it alone could take upwards of 30 seconds. Looking at systemd’s stack it was clear that it was busy processing these mount events as well and could lead to complete system lockup. Kubelet also timed out frequently talking to containerd in this period. Examining the mount table made it clear that these mounts were related to container creation.
The affected nodes were almost all r5.metal instances, and were starting applications whose container image contained many layers (50+).
Challenge
Mount Lock Contention
The flamegraph in Figure 1 clearly shows where containerd spent its time. Almost all of the time is spent trying to grab a kernel-level lock as part of the various mount-related activities when assembling the container’s root filesystem!
Figure 1: Flamegraph depicting lock contention
Looking closer, containerd executes the following calls for each layer if using user namespaces:
open_tree() to get a reference to the layer / directory
mount_setattr() to set the idmap to match the container’s user range, shifting the ownership so this container can access the files
move_mount() to create a bind mount on the host with this new idmap applied
These bind mounts are owned by the container’s user range and are then used as the lowerdirs to create the overlayfs-based rootfs for the container. Once the overlayfs rootfs is mounted, the bind mounts are then unmounted since they are not necessary to keep around once the overlayfs is constructed.
If a node is starting many containers at once, every CPU ends up busy trying to execute these mounts and umounts. The kernel VFS has various global locks related to the mount table, and each of these mounts requires taking that lock as we can see in the top of the flamegraph. Any system trying to quickly set up many containers is prone to this, and this is a function of the number of layers in the container image.
For example, assume a node is starting 100 containers, each with 50 layers in its image. Each container will need 50 bind mounts to do the idmap for each layer. The container’s overlayfs mount will be created using those bind mounts as the lower directories, and then all 50 bind mounts can be cleaned up via umount. Containerd actually goes through this process twice, once to determine some user information in the image and once to create the actual rootfs. This means the total number of mount operations on the start up path for our 100 containers is 100 * 2 * (1 + 50 + 50) = 20200 mounts, all of which require grabbing various global mount related locks!
Diagnosis
What’s Different In The New Runtime?
As alluded to in the introduction, Netflix has been undergoing a modernization of its container runtime. In the past a virtual kubelet + docker solution was used, whereas now a kubelet + containerd solution is being used. Both the old runtime and the new runtime used user namespaces, so what’s the difference here?
Old Runtime: All containers shared a single host user range. UIDs in image layers were shifted at untar time, so file permissions matched when containers accessed files. This worked because all containers used the same host user.
New Runtime: Each container gets a unique host user range, improving security — if a container escapes, it can only affect its own files. To avoid the costly process of untarring and shifting UIDs for every container, the new runtime uses the kernel’s idmap feature. This allows efficient UID mapping per container without copying or changing file ownership, which is why containerd performs many mounts.
Figure 2 below is a simplified example of how this idmap feature looks like:
Figure 2: idmap feature
Why Does Instance Type Matter?
As noted earlier, the issue was predominantly occurring on r5.metal instances. Once we identified the root issue we could easily reproduce by creating a container image with many layers and sending hundreds of workloads using the image to a test node.
To better understand why this bottleneck was more profound on some instances compared to others, we benchmarked container launches on different AWS instance types:
r5.metal (5th gen Intel, dual-socket, multiple NUMA domains)
m7i.metal-24xl (7th gen Intel, single-socket, single NUMA domain)
m7a.24xlarge (7th gen AMD, single-socket, single NUMA domain)
Baseline Results
Figure 3 shows the baseline results from scaling containers on each instance type
At low concurrency (≤ ~20 containers), all platforms performed similarly
As concurrency increased, r5.metal began to fail around 100 containers
7th generation AWS instances maintained lower launch times and higher success rates as concurrency grew
m7a instances showed the most consistent scaling behavior with the lowest failure rates even at high concurrency
Deep Dive
Using perf record and custom microbenchmarks, we can see the hottest code path was in the Linux kernel’s Virtual Filesystem (VFS) path lookup code — specifically, a tight spin loop waiting on a sequence lock in path_init(). The CPU spent most of its time executing the pause instruction, indicating many threads were spinning, waiting for the global lock, as shown in the disassembly snippet below
path_init():
…
mov mount_lock,%eax
test $0x1,%al
je 7c
pause
…
Using Intel’s Topdown Microarchitecture Analysis (TMA), we observed:
95.5% of pipeline slots were stalled on contested accesses (tma_contested_accesses).
57% of slots were due to false sharing (multiple cores accessing the same cache line).
Cache line bouncing and lock contention were the primary culprits.
Given a high amount of time being spent in contested accesses, the natural thinking from a perspective of hardware variations led to investigation of NUMA and Hyperthreading impact coming from the architecture to this subset
NUMA Effects
Non-Uniform Memory Access (NUMA) is a system design where each processor has its own local memory for faster access but relies on an interconnect to access the memory attached to a remote processor. Introduced in the 1990s to improve scalability in multiprocessor systems, NUMA boosts performance but also introduces higher latency when a CPU needs to access memory attached to another processor. Figure 4 is a simple image describing local vs remote access patterns of a NUMA architecture
AWS instances come in a variety of shapes and sizes. To obtain the largest core count, we tested the 2-socket 5th generation metal instances (r5.metal), on which containers were orchestrated by the titus agent. Modern dual-socket architectures implement NUMA design, leading to faster local but higher remote access latencies. Although container orchestration can maintain locality, global locks can easily run into high latency effects due to remote synchronization. In order to test the impact of NUMA, we tested an AWS 48xl sized instance with 2 NUMA nodes or sockets versus an AWS 24xl sized instance, which represents a single NUMA node or socket. As seen from Figure 5, the extra hop introduces high latencies and hence failures very quickly.
Figure 5: Numa Impact
Hyperthreading Effects
Hyperthreading (HT): Disabling HT on m7i.metal-24xl (Intel) improved container launch latencies by 20–30% as seen in Figure 6, since hyperthreads compete for shared execution resources, worsening the lock contention. When hyperthreading is enabled, each physical CPU core is split into two logical CPUs (hyperthreads) that share most of the core’s execution resources, such as caches, execution units, and memory bandwidth. While this can improve throughput for workloads that are not fully utilizing the core, it introduces significant challenges for workloads that rely heavily on global locks. By disabling hyperthreading, each thread runs on its own physical core, eliminating this competition for shared resources between hyperthreads. As a result, threads can acquire and release global locks more quickly, reducing overall contention and improving latency for operations that generally share underlying resources.
Figure 6: Hyperthreading impact
Why Does Hardware Architecture Matter?
Centralized Cache Architectures
Some modern server CPUs use a mesh-style interconnect to link cores and cache slices, with each intersection managing cache coherence for a subset of memory addresses. In these designs, all communication passes through a central queueing structure, which can only handle one request for a given address at a time. When a global lock (like the mount lock) is under heavy contention, all atomic operations targeting that lock are funneled through this single queue, causing requests to pile up and resulting in memory stalls and latency spikes.
In some well-known mesh-based architectures as shown in Figure 7 below, this central queue is called the “Table of Requests” (TOR), and it can become a surprising bottleneck when many threads are fighting for the same lock. If you’ve ever wondered why certain CPUs seem to “pause for breath” under heavy contention, this is often the culprit.
Some modern server CPUs use a distributed, chiplet-based architecture (Figure 8), where multiple core complexes, each with their own local last-level cache — are connected via a high-speed interconnect fabric. In these designs, cache coherence is managed within each core complex, and traffic between complexes is handled by a scalable control fabric. Unlike mesh-based architectures with centralized queueing structures, this distributed approach spreads contention across multiple domains, making severe stalls from global lock contention less likely. For those interested in the technical details, public documentation from major CPU vendors provides deeper insight into these distributed cache and chiplet designs.
Here is a comparison of the same workload run on m7i (centralized cache architecture) vs m7a (distributed cache architecture). Note that, in order to make it closely comparable, Hyperthreading (HT) was disabled on m7i, given previous regression seen in Figure 6, and experiments were run using same core counts. The result clearly shows a fairly consistent difference in performance of approximately 20% as shown in Figure 9
Figure 9: Architectural impact between m7i and m7a
Microbenchmark Results
To prove the above theory related to NUMA, HT and micro-architecture, we developed a small microbenchmark which basically invokes a given number of threads that then spins on a globally contended lock. Running the benchmark at increasing thread counts reveals the latency characteristics of the system under different scenarios. For example, Figure 10 below is the microbenchmark results with NUMA, HT and different microarchitectures.
Figure 10: Global lock contention benchmark results
Results from this custom synthetic benchmark (pause_bench) confirmed:
On r5.metal, eliminating NUMA by only using a single socket significantly drops latency at high thread counts
On m7i.metal-24xl, disabling hyperthreading further improves scaling
On m7a.24xlarge, performance scales the best, demonstrating that a distributed cache architecture handles cache-line contention in this case of global locks more gracefully.
Improving Software Architecture
While understanding the impacts of the hardware architecture is important for assessing possible mitigations, the root cause here is contention over a global lock. Working with containerd upstream we came to two possible solutions:
Use the newer kernel mount API’s fsconfig() lowerdir+ support to supply the idmap’ed lowerdirs as fd’s instead of filesystem paths. This avoids the move_mount() syscall mentioned prior which requires global locks to mount each layer to the mount table
Map the common parent directory of all the layers. This makes the number of mount operations go from O(n) to O(1) per container, where n is the number of layers in the image
Since using the newer API requires using a new kernel, we opted to make the latter change to benefit more of the community. With that in place, no longer do we see containerd’s flamegraph being dominated by mount-related operations. In fact, as seen in Figure 11 below we had to highlight them in purple below to see them at all!
Figure 11: Optimized solution
Conclusion
Our journey migrating to a modern kubelet + containerd runtime at Netflix revealed just how deeply intertwined software and hardware architecture can be when operating at scale. While kubelet/containerd’s usage of unique container users brought significant security gains, it also surfaced new bottlenecks rooted in kernel and CPU architecture — particularly when launching hundreds of many layered container images in parallel. Our investigation highlighted that not all hardware is created equal for this workload: centralized cache management amplified cache contention while distributed cache design smoothly scaled under load.
Ultimately, the best solution combined hardware awareness with software improvements. For an immediate mitigation we chose to route these workloads to CPU architectures that scaled better under these conditions. By changing the software design to minimize per-layer mount operations, we eliminated the global lock as a launch-time bottleneck — unlocking faster, more reliable scaling regardless of the underlying CPU architecture. This experience underscores the importance of holistic performance engineering: understanding and optimizing both the software stack and the hardware it runs on is key to delivering seamless user experiences at Netflix scale.
We trust these insights will assist others in navigating the evolving container ecosystem, transforming potential challenges into opportunities for building robust, high-performance platforms.
Special thanks to the Titus and Performance Engineering teams at Netflix.
Handling data in streams is fundamental to how we build applications. To make streaming work everywhere, the WHATWG Streams Standard (informally known as “Web streams”) was designed to establish a common API to work across browsers and servers. It shipped in browsers, was adopted by Cloudflare Workers, Node.js, Deno, and Bun, and became the foundation for APIs like fetch(). It’s a significant undertaking, and the people who designed it were solving hard problems with the constraints and tools they had at the time.
But after years of building on Web streams – implementing them in both Node.js and Cloudflare Workers, debugging production issues for customers and runtimes, and helping developers work through far too many common pitfalls – I’ve come to believe that the standard API has fundamental usability and performance issues that cannot be fixed easily with incremental improvements alone. The problems aren’t bugs; they’re consequences of design decisions that may have made sense a decade ago, but don’t align with how JavaScript developers write code today.
This post explores some of the fundamental issues I see with Web streams and presents an alternative approach built around JavaScript language primitives that demonstrate something better is possible.
In benchmarks, this alternative can run anywhere between 2x to 120x faster than Web streams in every runtime I’ve tested it on (including Cloudflare Workers, Node.js, Deno, Bun, and every major browser). The improvements are not due to clever optimizations, but fundamentally different design choices that more effectively leverage modern JavaScript language features. I’m not here to disparage the work that came before; I’m here to start a conversation about what can potentially come next.
Where we’re coming from
The Streams Standard was developed between 2014 and 2016 with an ambitious goal to provide “APIs for creating, composing, and consuming streams of data that map efficiently to low-level I/O primitives.” Before Web streams, the web platform had no standard way to work with streaming data.
Node.js already had its own streaming API at the time that was ported to also work in browsers, but WHATWG chose not to use it as a starting point given that it is chartered to only consider the needs of Web browsers. Server-side runtimes only adopted Web streams later, after Cloudflare Workers and Deno each emerged with first-class Web streams support and cross-runtime compatibility became a priority.
The design of Web streams predates async iteration in JavaScript. The for await...of syntax didn’t land until ES2018, two years after the Streams Standard was initially finalized. This timing meant the API couldn’t initially leverage what would eventually become the idiomatic way to consume asynchronous sequences in JavaScript. Instead, the spec introduced its own reader/writer acquisition model, and that decision rippled through every aspect of the API.
Excessive ceremony for common operations
The most common task with streams is reading them to completion. Here’s what that looks like with Web streams:
// First, we acquire a reader that gives an exclusive lock
// on the stream...
const reader = stream.getReader();
const chunks = [];
try {
  // Second, we repeatedly call read and await on the returned
  // promise to either yield a chunk of data or indicate we're
  // done.
  while (true) {
    const { value, done } = await reader.read();
    if (done) break;
    chunks.push(value);
  }
} finally {
  // Finally, we release the lock on the stream
  reader.releaseLock();
}
You might assume this pattern is inherent to streaming. It isn’t. The reader acquisition, the lock management, and the { value, done } protocol are all just design choices, not requirements. They are artifacts of how and when the Web streams spec was written. Async iteration exists precisely to handle sequences that arrive over time, but async iteration did not yet exist when the streams specification was written. The complexity here is pure API overhead, not fundamental necessity.
Consider the alternative approach now that Web streams now do support for await...of:
const chunks = [];
for await (const chunk of stream) {
  chunks.push(chunk);
}
This is better in that there is far less boilerplate, but it doesn’t solve everything. Async iteration was retrofitted onto an API that wasn’t designed for it, and it shows. Features like BYOB (bring your own buffer) reads aren’t accessible through iteration. The underlying complexity of readers, locks, and controllers are still there, just hidden. When something does go wrong, or when additional features of the API are needed, developers find themselves back in the weeds of the original API, trying to understand why their stream is “locked” or why releaseLock() didn’t do what they expected or hunting down bottlenecks in code they don’t control.
The locking problem
Web streams use a locking model to prevent multiple consumers from interleaving reads. When you call getReader(), the stream becomes locked. While locked, nothing else can read from the stream directly, pipe it, or even cancel it – only the code that is actually holding the reader can.
This sounds reasonable until you see how easily it goes wrong:
async function peekFirstChunk(stream) {
  const reader = stream.getReader();
  const { value } = await reader.read();
  // Oops — forgot to call reader.releaseLock()
  // And the reader is no longer available when we return
  return value;
}

const first = await peekFirstChunk(stream);
// TypeError: Cannot obtain lock — stream is permanently locked
for await (const chunk of stream) { /* never runs */ }
Forgetting releaseLock() permanently breaks the stream. The lockedproperty tells you that a stream is locked, but not why, by whom, or whether the lock is even still usable. Piping internally acquires locks, making streams unusable during pipe operations in ways that aren’t obvious.
The semantics around releasing locks with pending reads were also unclear for years. If you called read() but didn’t await it, then called releaseLock(), what happened? The spec was recently clarified to cancel pending reads on lock release – but implementations varied, and code that relied on the previous unspecified behavior can break.
That said, it’s important to recognize that locking in itself is not bad. It does, in fact, serve an important purpose to ensure that applications properly and orderly consume or produce data. The key challenge is with the original manual implementation of it using APIs like getReader() and releaseLock(). With the arrival of automatic lock and reader management with async iterables, dealing with locks from the users point of view became a lot easier.
For implementers, the locking model adds a fair amount of non-trivial internal bookkeeping. Every operation must check lock state, readers must be tracked, and the interplay between locks, cancellation, and error states creates a matrix of edge cases that must all be handled correctly.
BYOB: complexity without payoff
BYOB (bring your own buffer) reads were designed to let developers reuse memory buffers when reading from streams, an important optimization intended for high-throughput scenarios. The idea is sound: instead of allocating new buffers for each chunk, you provide your own buffer and the stream fills it.
In practice, (and yes, there are always exceptions to be found) BYOB is rarely used to any measurable benefit. The API is substantially more complex than default reads, requiring a separate reader type (ReadableStreamBYOBReader) and other specialized classes (e.g. ReadableStreamBYOBRequest), careful buffer lifecycle management, and understanding of ArrayBuffer detachment semantics. When you pass a buffer to a BYOB read, the buffer becomes detached – transferred to the stream – and you get back a different view over potentially different memory. This transfer-based model is error-prone and confusing:
const reader = stream.getReader({ mode: 'byob' });
const buffer = new ArrayBuffer(1024);
let view = new Uint8Array(buffer);

const result = await reader.read(view);
// 'view' should now be detached and unusable
// (it isn't always in every impl)
// result.value is a NEW view, possibly over different memory
view = result.value; // Must reassign
BYOB also can’t be used with async iteration or TransformStreams, so developers who want zero-copy reads are forced back into the manual reader loop.
For implementers, BYOB adds significant complexity. The stream must track pending BYOB requests, handle partial fills, manage buffer detachment correctly, and coordinate between the BYOB reader and the underlying source. The Web Platform Tests for readable byte streams include dedicated test files just for BYOB edge cases: detached buffers, bad views, response-after-enqueue ordering, and more.
BYOB ends up being complex for both users and implementers, yet sees little adoption in practice. Most developers stick with default reads and accept the allocation overhead.
Most userland implementations of custom ReadableStream instances do not typically bother with all the ceremony required to correctly implement both default and BYOB read support in a single stream – and for good reason. It’s difficult to get right and most of the time consuming code is typically going to fallback on the default read path. The example below shows what a “correct” implementation would need to do. It’s big, complex, and error prone, and not a level of complexity that the typical developer really wants to have to deal with:
new ReadableStream({
    type: 'bytes',

    async pull(controller: ReadableByteStreamController) {
      if (offset >= totalBytes) {
        controller.close();
        return;
      }

      // Check for BYOB request FIRST
      const byobRequest = controller.byobRequest;

      if (byobRequest) {
        // === BYOB PATH ===
        // Consumer provided a buffer - we MUST fill it (or part of it)
        const view = byobRequest.view!;
        const bytesAvailable = totalBytes - offset;
        const bytesToWrite = Math.min(view.byteLength, bytesAvailable);

        // Create a view into the consumer's buffer and fill it
        // not critical but safer when bytesToWrite != view.byteLength
        const dest = new Uint8Array(
          view.buffer,
          view.byteOffset,
          bytesToWrite
        );

        // Fill with sequential bytes (our "data source")
        // Can be any thing here that writes into the view
        for (let i = 0; i < bytesToWrite; i++) {
          dest[i] = (offset + i) & 0xFF;
        }

        offset += bytesToWrite;

        // Signal how many bytes we wrote
        byobRequest.respond(bytesToWrite);

      } else {
        // === DEFAULT READER PATH ===
        // No BYOB request - allocate and enqueue a chunk
        const bytesAvailable = totalBytes - offset;
        const chunkSize = Math.min(1024, bytesAvailable);

        const chunk = new Uint8Array(chunkSize);
        for (let i = 0; i < chunkSize; i++) {
          chunk[i] = (offset + i) & 0xFF;
        }

        offset += chunkSize;
        controller.enqueue(chunk);
      }
    },

    cancel(reason) {
      console.log('Stream canceled:', reason);
    }
  });
When a host runtime provides a byte-oriented ReadableStream from the runtime itself, for instance, as the body of a fetch Response, it is often far easier for the runtime itself to provide an optimized implementation of BYOB reads, but those still need to be capable of handling both default and BYOB reading patterns and that requirement brings with it a fair amount of complexity.
Backpressure: good in theory, broken in practice
Backpressure – the ability for a slow consumer to signal a fast producer to slow down – is a first-class concept in Web streams. In theory. In practice, the model has some serious flaws.
The primary signal is desiredSize on the controller. It can be positive (wants data), zero (at capacity), negative (over capacity), or null (closed). Producers are supposed to check this value and stop enqueueing when it’s not positive. But there’s nothing enforcing this: controller.enqueue() always succeeds, even when desiredSize is deeply negative.
new ReadableStream({
  start(controller) {
    // Nothing stops you from doing this
    while (true) {
      controller.enqueue(generateData()); // desiredSize: -999999
    }
  }
});
Stream implementations can and do ignore backpressure; and some spec-defined features explicitly break backpressure. tee(), for instance, creates two branches from a single stream. If one branch reads faster than the other, data accumulates in an internal buffer with no limit. A fast consumer can cause unbounded memory growth while the slow consumer catches up, and there’s no way to configure this or opt out beyond canceling the slower branch.
Web streams do provide clear mechanisms for tuning backpressure behavior in the form of the highWaterMark option and customizable size calculations, but these are just as easy to ignore as desiredSize, and many applications simply fail to pay attention to them.
The same issues exist on the WritableStream side. A WritableStream has a highWaterMark and desiredSize. There is a writer.ready promise that producers of data are supposed to pay attention but often don’t.
const writable = getWritableStreamSomehow();
const writer = writable.getWriter();

// Producers are supposed to wait for the writer.ready
// It is a promise that, when resolves, indicates that
// the writables internal backpressure is cleared and
// it is ok to write more data
await writer.ready;
await writer.write(...);
For implementers, backpressure adds complexity without providing guarantees. The machinery to track queue sizes, compute desiredSize, and invoke pull() at the right times must all be implemented correctly. However, since these signals are advisory, all that work doesn’t actually prevent the problems backpressure is supposed to solve.
The hidden cost of promises
The Web streams spec requires promise creation at numerous points, often in hot paths and often invisible to users. Each read() call doesn’t just return a promise; internally, the implementation creates additional promises for queue management, pull() coordination, and backpressure signaling.
This overhead is mandated by the spec’s reliance on promises for buffer management, completion, and backpressure signals. While some of it is implementation-specific, much of it is unavoidable if you’re following the spec as written. For high-frequency streaming – video frames, network packets, real-time data – this overhead is significant.
The problem compounds in pipelines. Each TransformStream adds another layer of promise machinery between source and sink. The spec doesn’t define synchronous fast paths, so even when data is available immediately, the promise machinery still runs.
For implementers, this promise-heavy design constrains optimization opportunities. The spec mandates specific promise resolution ordering, making it difficult to batch operations or skip unnecessary async boundaries without risking subtle compliance failures. There are many hidden internal optimizations that implementers do make but these can be complicated and difficult to get right.
While I was writing this blog post, Vercel’s Malte Ubl published their own blog post describing some research work Vercel has been doing around improving the performance of Node.js’ Web streams implementation. In that post they discuss the same fundamental performance optimization problem that every implementation of Web streams face:
“Or consider pipeTo(). Each chunk passes through a full Promise chain: read, write, check backpressure, repeat. An {value, done} result object is allocated per read. Error propagation creates additional Promise branches.
None of this is wrong. These guarantees matter in the browser where streams cross security boundaries, where cancellation semantics need to be airtight, where you do not control both ends of a pipe. But on the server, when you are piping React Server Components through three transforms at 1KB chunks, the cost adds up.
We benchmarked native WebStream pipeThrough at 630 MB/s for 1KB chunks. Node.js pipeline() with the same passthrough transform: ~7,900 MB/s. That is a 12x gap, and the difference is almost entirely Promise and object allocation overhead.”
– Malte Ubl, https://vercel.com/blog/we-ralph-wiggumed-webstreams-to-make-them-10x-faster
As part of their research, they have put together a set of proposed improvements for Node.js’ Web streams implementation that will eliminate promises in certain code paths which can yield a significant performance boost up to 10x faster, which only goes to prove the point: promises, while useful, add significant overhead. As one of the core maintainers of Node.js, I am looking forward to helping Malte and the folks at Vercel get their proposed improvements landed!
In a recent update made to Cloudflare Workers, I made similar kinds of modifications to an internal data pipeline that reduced the number of JavaScript promises created in certain application scenarios by up to 200x. The result is several orders of magnitude improvement in performance in those applications.
Real-world failures
Exhausting resources with unconsumed bodies
When fetch() returns a response, the body is a ReadableStream. If you only check the status and don’t consume or cancel the body, what happens? The answer varies by implementation, but a common outcome is resource leakage.
async function checkEndpoint(url) {
  const response = await fetch(url);
  return response.ok; // Body is never consumed or cancelled
}

// In a loop, this can exhaust connection pools
for (const url of urls) {
  await checkEndpoint(url);
}
This pattern has caused connection pool exhaustion in Node.js applications using undici (the fetch() implementation built into Node.js), and similar issues have appeared in other runtimes. The stream holds a reference to the underlying connection, and without explicit consumption or cancellation, the connection may linger until garbage collection – which may not happen soon enough under load.
The problem is compounded by APIs that implicitly create stream branches. Request.clone() and Response.clone() perform implicit tee() operations on the body stream – a detail that’s easy to miss. Code that clones a request for logging or retry logic may unknowingly create branched streams that need independent consumption, multiplying the resource management burden.
Now, to be certain, these types of issues are implementation bugs. The connection leak was definitely something that undici needed to fix in its own implementation, but the complexity of the specification does not make dealing with these types of issues easy.
“Cloning streams in Node.js’s fetch() implementation is harder than it looks. When you clone a request or response body, you’re calling tee() – which splits a single stream into two branches that both need to be consumed. If one consumer reads faster than the other, data buffers unbounded in memory waiting for the slow branch. If you don’t properly consume both branches, the underlying connection leaks. The coordination required between two readers sharing one source makes it easy to accidentally break the original request or exhaust connection pools. It’s a simple API call with complex underlying mechanics that are difficult to get right.” – Matteo Collina, Ph.D. – Platformatic Co-Founder & CTO, Node.js Technical Steering Committee Chair
Falling headlong off the tee() memory cliff
tee() splits a stream into two branches. It seems straightforward, but the implementation requires buffering: if one branch is read faster than the other, the data must be held somewhere until the slower branch catches up.
const [forHash, forStorage] = response.body.tee();

// Hash computation is fast
const hash = await computeHash(forHash);

// Storage write is slow — meanwhile, the entire stream
// may be buffered in memory waiting for this branch
await writeToStorage(forStorage);
The spec does not mandate buffer limits for tee(). And to be fair, the spec allows implementations to implement the actual internal mechanisms for tee()and other APIs in any way they see fit so long as the observable normative requirements of the specification are met. But if an implementation chooses to implement tee() in the specific way described by the streams specification, then tee() will come with a built-in memory management issue that is difficult to work around.
Implementations have had to develop their own strategies for dealing with this. Firefox initially used a linked-list approach that led to O(n) memory growth proportional to the consumption rate difference. In Cloudflare Workers, we opted to implement a shared buffer model where backpressure is signaled by the slowest consumer rather than the fastest.
Transform backpressure gaps
TransformStream creates a readable/writable pair with processing logic in between. The transform() function executes on write, not on read. Processing of the transform happens eagerly as data arrives, regardless of whether any consumer is ready. This causes unnecessary work when consumers are slow, and the backpressure signaling between the two sides has gaps that can cause unbounded buffering under load. The expectation in the spec is that the producer of the data being transformed is paying attention to the writer.ready signal on the writable side of the transform but quite often producers just simply ignore it.
If the transform’s transform() operation is synchronous and always enqueues output immediately, it never signals backpressure back to the writable side even when the downstream consumer is slow. This is a consequence of the spec design that many developers completely overlook. In browsers, where there’s only a single user and typically only a small number of stream pipelines active at any given time, this type of foot gun is often of no consequence, but it has a major impact on server-side or edge performance in runtimes that serve thousands of concurrent requests.
const fastTransform = new TransformStream({
  transform(chunk, controller) {
    // Synchronously enqueue — this never applies backpressure
    // Even if the readable side's buffer is full, this succeeds
    controller.enqueue(processChunk(chunk));
  }
});

// Pipe a fast source through the transform to a slow sink
fastSource
  .pipeThrough(fastTransform)
  .pipeTo(slowSink);  // Buffer grows without bound
What TransformStreams are supposed to do is check for backpressure on the controller and use promises to communicate that back to the writer:
const fastTransform = new TransformStream({
  async transform(chunk, controller) {
    if (controller.desiredSize <= 0) {
      // Wait on the backpressure to clear somehow
    }

    controller.enqueue(processChunk(chunk));
  }
});
A difficulty here, however, is that the TransformStreamDefaultController does not have a ready promise mechanism like Writers do; so the TransformStream implementation would need to implement a polling mechanism to periodically check when controller.desiredSize becomes positive again.
The problem gets worse in pipelines. When you chain multiple transforms – say, parse, transform, then serialize – each TransformStream has its own internal readable and writable buffers. If implementers follow the spec strictly, data cascades through these buffers in a push-oriented fashion: the source pushes to transform A, which pushes to transform B, which pushes to transform C, each accumulating data in intermediate buffers before the final consumer has even started pulling. With three transforms, you can have six internal buffers filling up simultaneously.
Developers using the streams API are expected to remember to use options like highWaterMark when creating their sources, transforms, and writable destinations but often they either forget or simply choose to ignore it.
source
  .pipeThrough(parse)      // buffers filling...
  .pipeThrough(transform)  // more buffers filling...
  .pipeThrough(serialize)  // even more buffers...
  .pipeTo(destination);    // consumer hasn't started yet
Implementations have found ways to optimize transform pipelines by collapsing identity transforms, short-circuiting non-observable paths, deferring buffer allocation, or falling back to native code that does not run JavaScript at all. Deno, Bun, and Cloudflare Workers have all successfully implemented “native path” optimizations that can help eliminate much of the overhead, and Vercel’s recent fast-webstreams research is working on similar optimizations for Node.js. But the optimizations themselves add significant complexity and still can’t fully escape the inherently push-oriented model that TransformStream uses.
GC thrashing in server-side rendering
Streaming server-side rendering (SSR) is a particularly painful case. A typical SSR stream might render thousands of small HTML fragments, each passing through the streams machinery:
// Each component enqueues a small chunk
function renderComponent(controller) {
  controller.enqueue(encoder.encode(`<div>${content}</div>`));
}

// Hundreds of components = hundreds of enqueue calls
// Each one triggers promise machinery internally
for (const component of components) {
  renderComponent(controller);  // Promises created, objects allocated
}
Every fragment means promises created for read() calls, promises for backpressure coordination, intermediate buffer allocations, and { value, done } result objects – most of which become garbage almost immediately.
Under load, this creates GC pressure that can devastate throughput. The JavaScript engine spends significant time collecting short-lived objects instead of doing useful work. Latency becomes unpredictable as GC pauses interrupt request handling. I’ve seen SSR workloads where garbage collection accounts for a substantial portion (up to and beyond 50%) of total CPU time per request. That’s time that could be spent actually rendering content.
The irony is that streaming SSR is supposed to improve performance by sending content incrementally. But the overhead of the streams machinery can negate those gains, especially for pages with many small components. Developers sometimes find that buffering the entire response is actually faster than streaming through Web streams, defeating the purpose entirely.
The optimization treadmill
To achieve usable performance, every major runtime has resorted to non-standard internal optimizations for Web streams. Node.js, Deno, Bun, and Cloudflare Workers have all developed their own workarounds. This is particularly true for streams wired up to system-level I/O, where much of the machinery is non-observable and can be short-circuited.
Finding these optimization opportunities can itself be a significant undertaking. It requires end-to-end understanding of the spec to identify which behaviors are observable and which can safely be elided. Even then, whether a given optimization is actually spec-compliant is often unclear. Implementers must make judgment calls about which semantics they can relax without breaking compatibility. This puts enormous pressure on runtime teams to become spec experts just to achieve acceptable performance.
These optimizations are difficult to implement, frequently error-prone, and lead to inconsistent behavior across runtimes. Bun’s “Direct Streams” optimization takes a deliberately and observably non-standard approach, bypassing much of the spec’s machinery entirely. Cloudflare Workers’ IdentityTransformStream provides a fast-path for pass-through transforms but is Workers-specific and implements behaviors that are not standard for a TransformStream. Each runtime has its own set of tricks and the natural tendency is toward non-standard solutions, because that’s often the only way to make things fast.
This fragmentation hurts portability. Code that performs well on one runtime may behave differently (or poorly) on another, even though it’s using “standard” APIs. The complexity burden on runtime implementers is substantial, and the subtle behavioral differences create friction for developers trying to write cross-runtime code, particularly those maintaining frameworks that must be able to run efficiently across many runtime environments.
It is also necessary to emphasize that many optimizations are only possible in parts of the spec that are unobservable to user code. The alternative, like Bun “Direct Streams”, is to intentionally diverge from the spec-defined observable behaviors. This means optimizations often feel “incomplete”. They work in some scenarios but not in others, in some runtimes but not others, etc. Every such case adds to the overall unsustainable complexity of the Web streams approach which is why most runtime implementers rarely put significant effort into further improvements to their streams implementations once the conformance tests are passing.
Implementers shouldn’t need to jump through these hoops. When you find yourself needing to relax or bypass spec semantics just to achieve reasonable performance, that’s a sign something is wrong with the spec itself. A well-designed streaming API should be efficient by default, not require each runtime to invent its own escape hatches.
The compliance burden
A complex spec creates complex edge cases. The Web Platform Tests for streams span over 70 test files, and while comprehensive testing is a good thing, what’s telling is what needs to be tested.
Consider some of the more obscure tests that implementations must pass:
Prototype pollution defense: One test patches Object.prototype.then to intercept promise resolutions, then verifies that pipeTo() and tee() operations don’t leak internal values through the prototype chain. This tests a security property that only exists because the spec’s promise-heavy internals create an attack surface.
WebAssembly memory rejection: BYOB reads must explicitly reject ArrayBuffers backed by WebAssembly memory, which look like regular buffers but can’t be transferred. This edge case exists because of the spec’s buffer detachment model – a simpler API wouldn’t need to handle it.
Crash regression for state machine conflicts: A test specifically checks that calling byobRequest.respond() after enqueue() doesn’t crash the runtime. This sequence creates a conflict in the internal state machine — the enqueue() fulfills the pending read and should invalidate the byobRequest, but implementations must gracefully handle the subsequent respond() rather than corrupting memory in order to cover the very likely possibility that developers are not using the complex API correctly.
These aren’t contrived scenarios invented by test authors in total vacuum. They’re consequences of the spec’s design and reflect real world bugs.
For runtime implementers, passing the WPT suite means handling intricate corner cases that most application code will never encounter. The tests encode not just the happy path but the full matrix of interactions between readers, writers, controllers, queues, strategies, and the promise machinery that connects them all.
A simpler API would mean fewer concepts, fewer interactions between concepts, and fewer edge cases to get right resulting in more confidence that implementations actually behave consistently.
The takeaway
Web streams are complex for users and implementers alike. The problems with the spec aren’t bugs. They emerge from using the API exactly as designed. They aren’t issues that can be fixed solely through incremental improvements. They’re consequences of fundamental design choices. To improve things we need different foundations.
A better streams API is possible
After implementing the Web streams spec multiple times across different runtimes and seeing the pain points firsthand, I decided it was time to explore what a better, alternative streaming API could look like if designed from first principles today.
What follows is a proof of concept: it’s not a finished standard, not a production-ready library, not even necessarily a concrete proposal for something new, but a starting point for discussion that demonstrates the problems with Web streams aren’t inherent to streaming itself; they’re consequences of specific design choices that could be made differently. Whether this exact API is the right answer is less important than whether it sparks a productive conversation about what we actually need from a streaming primitive.
What is a stream?
Before diving into API design, it’s worth asking: what is a stream?
At its core, a stream is just a sequence of data that arrives over time. You don’t have all of it at once. You process it incrementally as it becomes available.
Unix pipes are perhaps the purest expression of this idea:
cat access.log | grep "error" | sort | uniq -c
Data flows left to right. Each stage reads input, does its work, writes output. There’s no pipe reader to acquire, no controller lock to manage. If a downstream stage is slow, upstream stages naturally slow down as well. Backpressure is implicit in the model, not a separate mechanism to learn (or ignore).
In JavaScript, the natural primitive for “a sequence of things that arrive over time” is already in the language: the async iterable. You consume it with for await...of. You stop consuming by stopping iteration.
This is the intuition the new API tries to preserve: streams should feel like iteration, because that’s what they are. The complexity of Web streams – readers, writers, controllers, locks, queuing strategies – obscures this fundamental simplicity. A better API should make the simple case simple and only add complexity where it’s genuinely needed.
Design principles
I built the proof-of-concept alternative around a different set of principles.
Streams are iterables.
No custom ReadableStream class with hidden internal state. A readable stream is just an AsyncIterable<Uint8Array[]>. You consume it with for await...of. No readers to acquire, no locks to manage.
Pull-through transforms
Transforms don’t execute until the consumer pulls. There’s no eager evaluation, no hidden buffering. Data flows on-demand from source, through transforms, to the consumer. If you stop iterating, processing stops.
Explicit backpressure
Backpressure is strict by default. When a buffer is full, writes reject rather than silently accumulating. You can configure alternative policies – block until space is available, drop oldest, drop newest – but you have to choose explicitly. No more silent memory growth.
Batched chunks
Instead of yielding one chunk per iteration, streams yield Uint8Array[]: arrays of chunks. This amortizes the async overhead across multiple chunks, reducing promise creation and microtask latency in hot paths.
Bytes only
The API deals exclusively with bytes (Uint8Array). Strings are UTF-8 encoded automatically. There’s no “value stream” vs “byte stream” dichotomy. If you want to stream arbitrary JavaScript values, use async iterables directly. While the API uses Uint8Array, it treats chunks as opaque. There is no partial consumption, no BYOB patterns, no byte-level operations within the streaming machinery itself. Chunks go in, chunks come out, unchanged unless a transform explicitly modifies them.
Synchronous fast paths matter
The API recognizes that synchronous data sources are both necessary and common. The application should not be forced to always accept the performance cost of asynchronous scheduling simply because that’s the only option provided. At the same time, mixing sync and async processing can be dangerous. Synchronous paths should always be an option and should always be explicit.
The new API in action
Creating and consuming streams
In Web streams, creating a simple producer/consumer pair requires TransformStream, manual encoding, and careful lock management:
const { readable, writable } = new TransformStream();
const enc = new TextEncoder();
const writer = writable.getWriter();
await writer.write(enc.encode("Hello, World!"));
await writer.close();
writer.releaseLock();

const dec = new TextDecoder();
let text = '';
for await (const chunk of readable) {
  text += dec.decode(chunk, { stream: true });
}
text += dec.decode();
Even this relatively clean version requires: a TransformStream, manual TextEncoder and TextDecoder, and explicit lock release.
Here’s the equivalent with the new API:
import { Stream } from 'new-streams';

// Create a push stream
const { writer, readable } = Stream.push();

// Write data — backpressure is enforced
await writer.write("Hello, World!");
await writer.end();

// Consume as text
const text = await Stream.text(readable);
The readable is just an async iterable. You can pass it to any function that expects one, including Stream.text() which collects and decodes the entire stream.
The writer has a simple interface: write(), writev() for batched writes, end() to signal completion, and abort() for errors. That’s essentially it.
The Writer is not a concrete class. Any object that implements write(), end(), and abort() can be a writer making it easy to adapt existing APIs or create specialized implementations without subclassing. There’s no complex UnderlyingSink protocol with start(), write(), close(), and abort() callbacks that must coordinate through a controller whose lifecycle and state are independent of the WritableStream it is bound to.
Here’s a simple in-memory writer that collects all written data:
// A minimal writer implementation — just an object with methods
function createBufferWriter() {
  const chunks = [];
  let totalBytes = 0;
  let closed = false;

  const addChunk = (chunk) => {
    chunks.push(chunk);
    totalBytes += chunk.byteLength;
  };

  return {
    get desiredSize() { return closed ? null : 1; },

    // Async variants
    write(chunk) { addChunk(chunk); },
    writev(batch) { for (const c of batch) addChunk(c); },
    end() { closed = true; return totalBytes; },
    abort(reason) { closed = true; chunks.length = 0; },

    // Sync variants return boolean (true = accepted)
    writeSync(chunk) { addChunk(chunk); return true; },
    writevSync(batch) { for (const c of batch) addChunk(c); return true; },
    endSync() { closed = true; return totalBytes; },
    abortSync(reason) { closed = true; chunks.length = 0; return true; },

    getChunks() { return chunks; }
  };
}

// Use it
const writer = createBufferWriter();
await Stream.pipeTo(source, writer);
const allData = writer.getChunks();
No base class to extend, no abstract methods to implement, no controller to coordinate with. Just an object with the right shape.
Pull-through transforms
Under the new API design, transforms should not perform any work until the data is being consumed. This is a fundamental principle.
// Nothing executes until iteration begins
const output = Stream.pull(source, compress, encrypt);

// Transforms execute as we iterate
for await (const chunks of output) {
  for (const chunk of chunks) {
    process(chunk);
  }
}
Stream.pull() creates a lazy pipeline. The compress and encrypt transforms don’t run until you start iterating output. Each iteration pulls data through the pipeline on demand.
This is fundamentally different from Web streams’ pipeThrough(), which starts actively pumping data from the source to the transform as soon as you set up the pipe. Pull semantics mean you control when processing happens, and stopping iteration stops processing.
Transforms can be stateless or stateful. A stateless transform is just a function that takes chunks and returns transformed chunks:
// Stateless transform — a pure function
// Receives chunks or null (flush signal)
const toUpperCase = (chunks) => {
  if (chunks === null) return null; // End of stream
  return chunks.map(chunk => {
    const str = new TextDecoder().decode(chunk);
    return new TextEncoder().encode(str.toUpperCase());
  });
};

// Use it directly
const output = Stream.pull(source, toUpperCase);
Stateful transforms are simple objects with member functions that maintain state across calls:
// Stateful transform — a generator that wraps the source
function createLineParser() {
  // Helper to concatenate Uint8Arrays
  const concat = (...arrays) => {
    const result = new Uint8Array(arrays.reduce((n, a) => n + a.length, 0));
    let offset = 0;
    for (const arr of arrays) { result.set(arr, offset); offset += arr.length; }
    return result;
  };

  return {
    async *transform(source) {
      let pending = new Uint8Array(0);

      for await (const chunks of source) {
        if (chunks === null) {
          // Flush: yield any remaining data
          if (pending.length > 0) yield [pending];
          continue;
        }

        // Concatenate pending data with new chunks
        const combined = concat(pending, ...chunks);
        const lines = [];
        let start = 0;

        for (let i = 0; i < combined.length; i++) {
          if (combined[i] === 0x0a) { // newline
            lines.push(combined.slice(start, i));
            start = i + 1;
          }
        }

        pending = combined.slice(start);
        if (lines.length > 0) yield lines;
      }
    }
  };
}

const output = Stream.pull(source, createLineParser());
For transforms that need cleanup on abort, add an abort handler:
// Stateful transform with resource cleanup
function createGzipCompressor() {
  // Hypothetical compression API...
  const deflate = new Deflater({ gzip: true });

  return {
    async *transform(source) {
      for await (const chunks of source) {
        if (chunks === null) {
          // Flush: finalize compression
          deflate.push(new Uint8Array(0), true);
          if (deflate.result) yield [deflate.result];
        } else {
          for (const chunk of chunks) {
            deflate.push(chunk, false);
            if (deflate.result) yield [deflate.result];
          }
        }
      }
    },
    abort(reason) {
      // Clean up compressor resources on error/cancellation
    }
  };
}
For implementers, there’s no Transformer protocol with start(), transform(), flush() methods and controller coordination passed into a TransformStream class that has its own hidden state machine and buffering mechanisms. Transforms are just functions or simple objects: far simpler to implement and test.
Explicit backpressure policies
When a bounded buffer fills up and a producer wants to write more, there are only a few things you can do:
Reject the write: refuse to accept more data
Wait: block until space becomes available
Discard old data: evict what’s already buffered to make room
Discard new data: drop what’s incoming
That’s it. Any other response is either a variation of these (like “resize the buffer,” which is really just deferring the choice) or domain-specific logic that doesn’t belong in a general streaming primitive. Web streams currently always choose Wait by default.
The new API makes you choose one of these four explicitly:
strict (default): Rejects writes when the buffer is full and too many writes are pending. Catches “fire-and-forget” patterns where producers ignore backpressure.
block: Writes wait until buffer space is available. Use when you trust the producer to await writes properly.
drop-oldest: Drops the oldest buffered data to make room. Useful for live feeds where stale data loses value.
drop-newest: Discards incoming data when full. Useful when you want to process what you have without being overwhelmed.
Instead of tee() with its hidden unbounded buffer, you get explicit multi-consumer primitives. Stream.share() is pull-based: consumers pull from a shared source, and you configure the buffer limits and backpressure policy upfront.
There’s also Stream.broadcast() for push-based multi-consumer scenarios. Both require you to think about what happens when consumers run at different speeds, because that’s a real concern that shouldn’t be hidden.
Sync/async separation
Not all streaming workloads involve I/O. When your source is in-memory and your transforms are pure functions, async machinery adds overhead without benefit. You’re paying for coordination of “waiting” that adds no benefit.
The new API has complete parallel sync versions: Stream.pullSync(), Stream.bytesSync(), Stream.textSync(), and so on. If your source and transforms are all synchronous, you can process the entire pipeline without a single promise.
// Async — when source or transforms may be asynchronous
const textAsync = await Stream.text(source);

// Sync — when all components are synchronous
const textSync = Stream.textSync(source);
Here’s a complete synchronous pipeline – compression, transformation, and consumption with zero async overhead:
// Synchronous source from in-memory data
const source = Stream.fromSync([inputBuffer]);

// Synchronous transforms
const compressed = Stream.pullSync(source, zlibCompressSync);
const encrypted = Stream.pullSync(compressed, aesEncryptSync);

// Synchronous consumption — no promises, no event loop trips
const result = Stream.bytesSync(encrypted);
The entire pipeline executes in a single call stack. No promises are created, no microtask queue scheduling occurs, and no GC pressure from short-lived async machinery. For CPU-bound workloads like parsing, compression, or transformation of in-memory data, this can be significantly faster than the equivalent Web streams code – which would force async boundaries even when every component is synchronous.
Web streams has no synchronous path. Even if your source has data ready and your transform is a pure function, you still pay for promise creation and microtask scheduling on every operation. Promises are fantastic for cases in which waiting is actually necessary, but they aren’t always necessary. The new API lets you stay in sync-land when that’s what you need.
Bridging the gap between this and web streams
The async iterator based approach provides a natural bridge between this alternative approach and Web streams. When coming from a ReadableStream to this new approach, simply passing the readable in as input works as expected when the ReadableStream is set up to yield bytes:
const readable = getWebReadableStreamSomehow();
const input = Stream.pull(readable, transform1, transform2);
for await (const chunks of input) {
  // process chunks
}
When adapting to a ReadableStream, a bit more work is required since the alternative approach yields batches of chunks, but the adaptation layer is as easily straightforward:
async function* adapt(input) {
  for await (const chunks of input) {
    for (const chunk of chunks) {
      yield chunk;
    }
  }
}

const input = Stream.pull(source, transform1, transform2);
const readable = ReadableStream.from(adapt(input));
How this addresses the real-world failures from earlier
Unconsumed bodies: Pull semantics mean nothing happens until you iterate. No hidden resource retention. If you don’t consume a stream, there’s no background machinery holding connections open.
The tee() memory cliff: Stream.share() requires explicit buffer configuration. You choose the highWaterMark and backpressure policy upfront: no more silent unbounded growth when consumers run at different speeds.
Transform backpressure gaps: Pull-through transforms execute on-demand. Data doesn’t cascade through intermediate buffers; it flows only when the consumer pulls. Stop iterating, stop processing.
GC thrashing in SSR: Batched chunks (Uint8Array[]) amortize async overhead. Sync pipelines via Stream.pullSync() eliminate promise allocation entirely for CPU-bound workloads.
Performance
The design choices have performance implications. Here are benchmarks from the reference implementation of this possible alternative compared to Web streams (Node.js v24.x, Apple M1 Pro, averaged over 10 runs):
Scenario
Alternative
Web streams
Difference
Small chunks (1KB × 5000)
~13 GB/s
~4 GB/s
~3× faster
Tiny chunks (100B × 10000)
~4 GB/s
~450 MB/s
~8× faster
Async iteration (8KB × 1000)
~530 GB/s
~35 GB/s
~15× faster
Chained 3× transforms (8KB × 500)
~275 GB/s
~3 GB/s
~80–90× faster
High-frequency (64B × 20000)
~7.5 GB/s
~280 MB/s
~25× faster
The chained transform result is particularly striking: pull-through semantics eliminate the intermediate buffering that plagues Web streams pipelines. Instead of each TransformStream eagerly filling its internal buffers, data flows on-demand from consumer to source.
Now, to be fair, Node.js really has not yet put significant effort into fully optimizing the performance of its Web streams implementation. There’s likely significant room for improvement in Node.js’ performance results through a bit of applied effort to optimize the hot paths there. That said, running these benchmarks in Deno and Bun also show a significant performance improvement with this alternative iterator based approach than in either of their Web streams implementations as well.
Browser benchmarks (Chrome/Blink, averaged over 3 runs) show consistent gains as well:
Scenario
Alternative
Web streams
Difference
Push 3KB chunks
~135k ops/s
~24k ops/s
~5–6× faster
Push 100KB chunks
~24k ops/s
~3k ops/s
~7–8× faster
3 transform chain
~4.6k ops/s
~880 ops/s
~5× faster
5 transform chain
~2.4k ops/s
~550 ops/s
~4× faster
bytes() consumption
~73k ops/s
~11k ops/s
~6–7× faster
Async iteration
~1.1M ops/s
~10k ops/s
~40–100× faster
These benchmarks measure throughput in controlled scenarios; real-world performance depends on your specific use case. The difference between Node.js and browser gains reflects the distinct optimization paths each environment takes for Web streams.
It’s worth noting that these benchmarks compare a pure TypeScript/JavaScript implementation of the new API against the native (JavaScript/C++/Rust) implementations of Web streams in each runtime. The new API’s reference implementation has had no performance optimization work; the gains come entirely from the design. A native implementation would likely show further improvement.
The gains illustrate how fundamental design choices compound: batching amortizes async overhead, pull semantics eliminate intermediate buffering, and the freedom for implementations to use synchronous fast paths when data is available immediately all contribute.
“We’ve done a lot to improve performance and consistency in Node streams, but there’s something uniquely powerful about starting from scratch. New streams’ approach embraces modern runtime realities without legacy baggage, and that opens the door to a simpler, performant and more coherent streams model.”
– Robert Nagy, Node.js TSC member and Node.js streams contributor
What’s next
I’m publishing this to start a conversation. What did I get right? What did I miss? Are there use cases that don’t fit this model? What would a migration path for this approach look like? The goal is to gather feedback from developers who’ve felt the pain of Web streams and have opinions about what a better API should look like.
API Reference: See the API.md for complete documentation
Examples: The samples directory has working code for common patterns
I welcome issues, discussions, and pull requests. If you’ve run into Web streams problems I haven’t covered, or if you see gaps in this approach, let me know. But again, the idea here is not to say “Let’s all use this shiny new object!”; it is to kick off a discussion that looks beyond the current status quo of Web Streams and returns back to first principles.
Web streams was an ambitious project that brought streaming to the web platform when nothing else existed. The people who designed it made reasonable choices given the constraints of 2014 – before async iteration, before years of production experience revealed the edge cases.
But we’ve learned a lot since then. JavaScript has evolved. A streaming API designed today can be simpler, more aligned with the language, and more explicit about the things that matter, like backpressure and multi-consumer behavior.
We deserve a better stream API. So let’s talk about what that could look like.
*This post was updated at 12:35 pm PT to fix a typo in the build time benchmarks.
Last week, one engineer and an AI model rebuilt the most popular front-end framework from scratch. The result, vinext (pronounced “vee-next”), is a drop-in replacement for Next.js, built on Vite, that deploys to Cloudflare Workers with a single command. In early benchmarks, it builds production apps up to 4x faster and produces client bundles up to 57% smaller. And we already have customers running it in production.
The whole thing cost about $1,100 in tokens.
The Next.js deployment problem
Next.js is the most popular React framework. Millions of developers use it. It powers a huge chunk of the production web, and for good reason. The developer experience is top-notch.
But Next.js has a deployment problem when used in the broader serverless ecosystem. The tooling is entirely bespoke: Next.js has invested heavily in Turbopack but if you want to deploy it to Cloudflare, Netlify, or AWS Lambda, you have to take that build output and reshape it into something the target platform can actually run.
If you’re thinking: “Isn’t that what OpenNext does?”, you are correct.
That is indeed the problem OpenNext was built to solve. And a lot of engineering effort has gone into OpenNext from multiple providers, including us at Cloudflare. It works, but quickly runs into limitations and becomes a game of whack-a-mole.
Building on top of Next.js output as a foundation has proven to be a difficult and fragile approach. Because OpenNext has to reverse-engineer Next.js’s build output, this results in unpredictable changes between versions that take a lot of work to correct.
Next.js has been working on a first-class adapters API, and we’ve been collaborating with them on it. It’s still an early effort but even with adapters, you’re still building on the bespoke Turbopack toolchain. And adapters only cover build and deploy. During development, next dev runs exclusively in Node.js with no way to plug in a different runtime. If your application uses platform-specific APIs like Durable Objects, KV, or AI bindings, you can’t test that code in dev without workarounds.
Introducing vinext
What if instead of adapting Next.js output, we reimplemented the Next.js API surface on Vite directly? Vite is the build tool used by most of the front-end ecosystem outside of Next.js, powering frameworks like Astro, SvelteKit, Nuxt, and Remix. A clean reimplementation, not merely a wrapper or adapter. We honestly didn’t think it would work. But it’s 2026, and the cost of building software has completely changed.
We got a lot further than we expected.
npm install vinext
Replace next with vinext in your scripts and everything else stays the same. Your existing app/, pages/, and next.config.js work as-is.
vinext dev          # Development server with HMR
vinext build        # Production build
vinext deploy       # Build and deploy to Cloudflare Workers
This is not a wrapper around Next.js and Turbopack output. It’s an alternative implementation of the API surface: routing, server rendering, React Server Components, server actions, caching, middleware. All of it built on top of Vite as a plugin. Most importantly Vite output runs on any platform thanks to the Vite Environment API.
The numbers
Early benchmarks are promising. We compared vinext against Next.js 16 using a shared 33-route App Router application.
Both frameworks are doing the same work: compiling, bundling, and preparing server-rendered routes. We disabled TypeScript type checking and ESLint in Next.js’s build (Vite doesn’t run these during builds), and used force-dynamic so Next.js doesn’t spend extra time pre-rendering static routes, which would unfairly slow down its numbers. The goal was to measure only bundler and compilation speed, nothing else. Benchmarks run on GitHub CI on every merge to main.
Production build time:
Framework
Mean
vs Next.js
Next.js 16.1.6 (Turbopack)
7.38s
baseline
vinext (Vite 7 / Rollup)
4.64s
1.6x faster
vinext (Vite 8 / Rolldown)
1.67s
4.4x faster
Client bundle size (gzipped):
Framework
Gzipped
vs Next.js
Next.js 16.1.6
168.9 KB
baseline
vinext (Rollup)
74.0 KB
56% smaller
vinext (Rolldown)
72.9 KB
57% smaller
These benchmarks measure compilation and bundling speed, not production serving performance. The test fixture is a single 33-route app, not a representative sample of all production applications. We expect these numbers to evolve as three projects continue to develop. The full methodology and historical results are public. Take them as directional, not definitive.
The direction is encouraging, though. Vite’s architecture, and especially Rolldown (the Rust-based bundler coming in Vite 8), has structural advantages for build performance that show up clearly here.
Deploying to Cloudflare Workers
vinext is built with Cloudflare Workers as the first deployment target. A single command takes you from source code to a running Worker:
vinext deploy
This handles everything: builds the application, auto-generates the Worker configuration, and deploys. Both the App Router and Pages Router work on Workers, with full client-side hydration, interactive components, client-side navigation, React state.
For production caching, vinext includes a Cloudflare KV cache handler that gives you ISR (Incremental Static Regeneration) out of the box:
import { KVCacheHandler } from "vinext/cloudflare";
import { setCacheHandler } from "next/cache";

setCacheHandler(new KVCacheHandler(env.MY_KV_NAMESPACE));
KV is a good default for most applications, but the caching layer is designed to be pluggable. That setCacheHandler call means you can swap in whatever backend makes sense. R2 might be a better fit for apps with large cached payloads or different access patterns. We’re also working on improvements to our Cache API that should provide a strong caching layer with less configuration. The goal is flexibility: pick the caching strategy that fits your app.
We also have a live example of Cloudflare Agents running in a Next.js app, without the need for workarounds like getPlatformProxy, since the entire app now runs in workerd, during both dev and deploy phases. This means being able to use Durable Objects, AI bindings, and every other Cloudflare-specific service without compromise. Have a look here.
Frameworks are a team sport
The current deployment target is Cloudflare Workers, but that’s a small part of the picture. Something like 95% of vinext is pure Vite. The routing, the module shims, the SSR pipeline, the RSC integration: none of it is Cloudflare-specific.
Cloudflare is looking to work with other hosting providers about adopting this toolchain for their customers (the lift is minimal — we got a proof-of-concept working on Vercel in less than 30 minutes!). This is an open-source project, and for its long term success, we believe it’s important we work with partners across the ecosystem to ensure ongoing investment. PRs from other platforms are welcome. If you’re interested in adding a deployment target, open an issue or reach out.
Status: Experimental
We want to be clear: vinext is experimental. It’s not even one week old, and it has not yet been battle-tested with any meaningful traffic at scale. If you’re evaluating it for a production application, proceed with appropriate caution.
That said, the test suite is extensive: over 1,700 Vitest tests and 380 Playwright E2E tests, including tests ported directly from the Next.js test suite and OpenNext’s Cloudflare conformance suite. We’ve verified it against the Next.js App Router Playground. Coverage sits at 94% of the Next.js 16 API surface.
Early results from real-world customers are encouraging. We’ve been working with National Design Studio, a team that’s aiming to modernize every government interface, on one of their beta sites, CIO.gov. They’re already running vinext in production, with meaningful improvements in build times and bundle sizes.
vinext already supports Incremental Static Regeneration (ISR) out of the box. After the first request to any page, it’s cached and revalidated in the background, just like Next.js. That part works today.
vinext does not yet support static pre-rendering at build time. In Next.js, pages without dynamic data get rendered during next build and served as static HTML. If you have dynamic routes, you use generateStaticParams() to enumerate which pages to build ahead of time. vinext doesn’t do that… yet.
This was an intentional design decision for launch. It’s on the roadmap, but if your site is 100% prebuilt HTML with static content, you probably won’t see much benefit from vinext today. That said, if one engineer can spend $1,100 in tokens and rebuild Next.js, you can probably spend $10 and migrate to a Vite-based framework designed specifically for static content, like Astro (which also deploys to Cloudflare Workers).
For sites that aren’t purely static, though, we think we can do something better than pre-rendering everything at build time.
Introducing Traffic-aware Pre-Rendering
Next.js pre-renders every page listed in generateStaticParams() during the build. A site with 10,000 product pages means 10,000 renders at build time, even though 99% of those pages may never receive a request. Builds scale linearly with page count. This is why large Next.js sites end up with 30-minute builds.
So we built Traffic-aware Pre-Rendering (TPR). It’s experimental today, and we plan to make it the default once we have more real-world testing behind it.
The idea is simple. Cloudflare is already the reverse proxy for your site. We have your traffic data. We know which pages actually get visited. So instead of pre-rendering everything or pre-rendering nothing, vinext queries Cloudflare’s zone analytics at deploy time and pre-renders only the pages that matter.
For a site with 100,000 product pages, the power law means 90% of traffic usually goes to 50 to 200 pages. Those get pre-rendered in seconds. Everything else falls back to on-demand SSR and gets cached via ISR after the first request. Every new deploy refreshes the set based on current traffic patterns. Pages that go viral get picked up automatically. All of this works without generateStaticParams() and without coupling your build to your production database.
Taking on the Next.js challenge, but this time with AI
A project like this would normally take a team of engineers months, if not years. Several teams at various companies have attempted it, and the scope is just enormous. We tried once at Cloudflare! Two routers, 33+ module shims, server rendering pipelines, RSC streaming, file-system routing, middleware, caching, static export. There’s a reason nobody has pulled it off.
This time we did it in under a week. One engineer (technically engineering manager) directing AI.
The first commit landed on February 13. By the end of that same evening, both the Pages Router and App Router had basic SSR working, along with middleware, server actions, and streaming. By the next afternoon, App Router Playground was rendering 10 of 11 routes. By day three, vinext deploy was shipping apps to Cloudflare Workers with full client hydration. The rest of the week was hardening: fixing edge cases, expanding the test suite, bringing API coverage to 94%.
What changed from those earlier attempts? AI got better. Way better.
Why this problem is made for AI
Not every project would go this way. This one did because a few things happened to line up at the right time.
Next.js is well-specified. It has extensive documentation, a massive user base, and years of Stack Overflow answers and tutorials. The API surface is all over the training data. When you ask Claude to implement getServerSideProps or explain how useRouter works, it doesn’t hallucinate. It knows how Next works.
Next.js has an elaborate test suite. The Next.js repo contains thousands of E2E tests covering every feature and edge case. We ported tests directly from their suite (you can see the attribution in the code). This gave us a specification we could verify against mechanically.
Vite is an excellent foundation.Vite handles the hard parts of front-end tooling: fast HMR, native ESM, a clean plugin API, production bundling. We didn’t have to build a bundler. We just had to teach it to speak Next.js. @vitejs/plugin-rsc is still early, but it gave us React Server Components support without having to build an RSC implementation from scratch.
The models caught up. We don’t think this would have been possible even a few months ago. Earlier models couldn’t sustain coherence across a codebase this size. New models can hold the full architecture in context, reason about how modules interact, and produce correct code often enough to keep momentum going. At times, I saw it go into Next, Vite, and React internals to figure out a bug. The state-of-the-art models are impressive, and they seem to keep getting better.
All of those things had to be true at the same time. Well-documented target API, comprehensive test suite, solid build tool underneath, and a model that could actually handle the complexity. Take any one of them away and this doesn’t work nearly as well.
How we actually built it
Almost every line of code in vinext was written by AI. But here’s the thing that matters more: every line passes the same quality gates you’d expect from human-written code. The project has 1,700+ Vitest tests, 380 Playwright E2E tests, full TypeScript type checking via tsgo, and linting via oxlint. Continuous integration runs all of it on every pull request. Establishing a set of good guardrails is critical to making AI productive in a codebase.
The process started with a plan. I spent a couple of hours going back and forth with Claude in OpenCode to define the architecture: what to build, in what order, which abstractions to use. That plan became the north star. From there, the workflow was straightforward:
Define a task (“implement the next/navigation shim with usePathname, useSearchParams, useRouter“).
Let the AI write the implementation and tests.
Run the test suite.
If tests pass, merge. If not, give the AI the error output and let it iterate.
Repeat.
We wired up AI agents for code review too. When a PR was opened, an agent reviewed it. When review comments came back, another agent addressed them. The feedback loop was mostly automated.
It didn’t work perfectly every time. There were PRs that were just wrong. The AI would confidently implement something that seemed right but didn’t match actual Next.js behavior. I had to course-correct regularly. Architecture decisions, prioritization, knowing when the AI was headed down a dead end: that was all me. When you give AI good direction, good context, and good guardrails, it can be very productive. But the human still has to steer.
For browser-level testing, I used agent-browser to verify actual rendered output, client-side navigation, and hydration behavior. Unit tests miss a lot of subtle browser issues. This caught them.
Over the course of the project, we ran over 800 sessions in OpenCode. Total cost: roughly $1,100 in Claude API tokens.
What this means for software
Why do we have so many layers in the stack? This project forced me to think deeply about this question. And to consider how AI impacts the answer.
Most abstractions in software exist because humans need help. We couldn’t hold the whole system in our heads, so we built layers to manage the complexity for us. Each layer made the next person’s job easier. That’s how you end up with frameworks on top of frameworks, wrapper libraries, thousands of lines of glue code.
AI doesn’t have the same limitation. It can hold the whole system in context and just write the code. It doesn’t need an intermediate framework to stay organized. It just needs a spec and a foundation to build on.
It’s not clear yet which abstractions are truly foundational and which ones were just crutches for human cognition. That line is going to shift a lot over the next few years. But vinext is a data point. We took an API contract, a build tool, and an AI model, and the AI wrote everything in between. No intermediate framework needed. We think this pattern will repeat across a lot of software. The layers we’ve built up over the years aren’t all going to make it.
Acknowledgments
Thanks to the Vite team. Vite is the foundation this whole thing stands on. @vitejs/plugin-rsc is still early days, but it gave me RSC support without having to build that from scratch, which would have been a dealbreaker. The Vite maintainers were responsive and helpful as I pushed the plugin into territory it hadn’t been tested in before.
We also want to acknowledge the Next.js team. They’ve spent years building a framework that raised the bar for what React development could look like. The fact that their API surface is so well-documented and their test suite so comprehensive is a big part of what made this project possible. vinext wouldn’t exist without the standard they set.
Try it
vinext includes an Agent Skill that handles migration for you. It works with Claude Code, OpenCode, Cursor, Codex, and dozens of other AI coding tools. Install it, open your Next.js project, and tell the AI to migrate:
npx skills add cloudflare/vinext
Then open your Next.js project in any supported tool and say:
migrate this project to vinext
The skill handles compatibility checking, dependency installation, config generation, and dev server startup. It knows what vinext supports and will flag anything that needs manual attention.
Or if you prefer doing it by hand:
npx vinext init    # Migrate an existing Next.js project
npx vinext dev     # Start the dev server
npx vinext deploy  # Ship to Cloudflare Workers
Today, we are launching Local Uploads for R2 in open beta. With Local Uploads enabled, object data is automatically written to a storage location close to the client first, then asynchronously copied to where the bucket lives. The data is immediately accessible and stays strongly consistent. Uploads get faster, and data feels global.
For many applications, performance needs to be global. Users uploading media content from different regions, for example, or devices sending logs and telemetry from all around the world. But your data has to live somewhere, and that means uploads from far away have to travel the full distance to reach your bucket.
R2 is object storage built on Cloudflare’s global network. Out of the box, it automatically caches object data globally for fast reads anywhere — all while retaining strong consistency and zero egress fees. This happens behind the scenes whether you’re using the S3 API, Workers Bindings, or plain HTTP. And now with Local Uploads, both reads and writes can be fast from anywhere in the world.
Try it yourself in this demo to see the benefits of Local Uploads.
Ready to try it? Enable Local Uploads in the Cloudflare Dashboard under your bucket’s settings, or with a single Wrangler command on an existing bucket.
75% lower total request duration for global uploads
Local Uploads makes upload requests (i.e. PutObject, UploadPart) faster. In both our private beta tests with customers and our synthetic benchmarks, we saw up to 75% reduction in Time to Last Byte (TTLB) when upload requests are made in a different region than the bucket. In these results, TTLB is measured from when R2 receives the upload request to when R2 returns a 200 response.
In our synthetic tests, we measured the impact of Local Uploads by using a synthetic workload to simulate a cross-region upload workflow. We deployed a test client in Western North America and configured an R2 bucket with a location hint for Asia-Pacific. The client performed around 20 PutObject requests per second over 30 minutes to upload objects of 5 MB size.
The following graph compares the p50 (or median) TTLB metrics for these requests, showing the difference in upload request duration — first without Local Uploads (TTLB around 2s), and then with Local Uploads enabled (TTLB around 500ms):
How it works: The distance problem
To understand how Local Uploads can improve upload requests, let’s first take a look at how R2 works. R2’s architecture is composed of multiple components including:
R2 Gateway Worker: The entry point for all API requests that handles authentication and routing logic. It is deployed across Cloudflare’s global network via Cloudflare Workers.
Durable Object Metadata Service: A distributed layer built on Durable Objects used to store and manage object metadata (e.g. object key, checksum).
Distributed Storage Infrastructure: The underlying infrastructure that persistently stores encrypted object data.
Without Local Uploads, here’s what happens when you upload objects to your bucket: The request is first received by the R2 Gateway, close to the user, where it is authenticated. Then, as the client streams bytes of the object data, the data is encrypted and written into the storage infrastructure in the region where the bucket is placed. When this is completed, the Gateway reaches out to the Metadata Service to publish the object metadata, and it returns a success response back to the client after it is committed.
If the client and the bucket are in separate regions, more variability can be introduced in the process of uploading bytes of the object data, due to the longer distance that the request must travel. This could result in slower or less reliable uploads.
A client uploading from Eastern North America to a bucket in Eastern Europe without Local Uploads enabled.
Now, when you make an upload request to a bucket with Local Uploads enabled, there are two cases that are handled:
The client and the bucket region are in the same region
The client and the bucket region are in different regions
In the first case, R2 follows the regular flow, where object data is written to the storage infrastructure for your bucket. In the second case, R2 writes to the storage infrastructure located in the client region while still publishing to the object metadata to the region of the bucket.
Importantly, the object is immediately accessible after the initial write completes. It remains accessible throughout the entire replication process — there’s nowaiting period for background replication to finish before the object can be read.
A client uploading from Eastern North America to a bucket in Eastern Europe with Local Uploads enabled.
Note that this is for non-jurisdiction restricted buckets, and Local Uploads are not available for buckets with jurisdiction restriction (e.g. EU, FedRAMP) enabled.
When to use Local Uploads
Local uploads are built for workloads that receive a lot of upload requests originating from different geographic regions than where your bucket is located. This feature is ideal when:
Your users are globally distributed
Upload performance and reliability is critical to your application
You want to optimize write performance without changing your bucket’s primary location
To understand the geographic distribution of where your read and write requests are initiated, you can visit the Cloudflare Dashboard, and go to your R2 bucket’s Metrics page and view the Request Distribution by Region graph.
How we built Local Uploads
With Local Uploads, object data is written close to the client and then copied to the bucket’s region in the background. We call this copy job a replication task.
Given these replication tasks, we needed an asynchronous processing component for them, which tends to be a great use case for Cloudflare Queues. Queues allow us to control the rate at which we process replication tasks, and it provides built-in failure handling capabilities like retries and dead letter queues. In this case, R2 shards replication tasks across multiple queues per storage region.
Publishing metadata and scheduling replication
When publishing the metadata of an object with Local Uploads enabled, we perform three operations atomically:
Store the object metadata
Create a pending replica key that tracks which replications still need to happen
Create a replication task marker keyed by timestamp, which controls when the task should be sent to the queue
The pending replica key contains the full replication plan: the number of replication tasks, which source location to read from, which destination location to write to, the replication mode and priority, and whether the source should be deleted after successful replication.
This gives us flexibility in how we move an object’s data. For example, moving data across long geographical distances is expensive. We could try to move all the replicas as fast as possible by processing them in parallel, but this would incur greater cost and pressure the network infrastructure. Instead, we minimize the number of cross-regional data movements by first creating one replica in the target bucket region, and then use this local copy to create additional replicas within the bucket region.
A background process periodically scans the replication task markers and sends them to one of the queues associated with the destination storage region. The markers guarantee at-least-once delivery to the queue — if enqueueing fails or the process crashes, the marker persists and the task will be retried on the next scan. This also allows us to process replications at different times and enqueue only valid tasks. Once a replication task reaches a queue, it is ready to be processed.
Asynchronous replication: Pull model
For the queue consumer, we chose a pull model where a centralized polling service consumes tasks from the regional queues and dispatches them to the Gateway Worker for execution.
Here’s how it works:
Polling service pulls from a regional queue: The consumer service polls the regional queue for replication tasks. It then batches the tasks to create uniform batch sizes based on the amount of data to be moved.
Polling service dispatches to Gateway Worker: The consumer service sends the replication job to the Gateway Worker.
Gateway Worker executes replication: The worker reads object data from the source location, writes it to the destination, and updates metadata in the Durable Object, optionally marking the source location to be garbage collected.
Gateway Worker reports result: On completion, the worker returns the result to the poller, which acknowledges the task to the queue as completed or failed.
By using this pull model approach, we ensure that the replication process remains stable and efficient. The service can dynamically adjust its pace based on real-time system health, guaranteeing that data is safely replicated across regions.
Try it out
Local Uploads is available now in open beta. There is no additional cost to enable Local Uploads. Upload requests made with this feature enabled incur the standard Class A operation costs, same as upload requests made without Local Uploads.
To get started, visit the Cloudflare Dashboard under your bucket’s settings and look for the Local Uploads card to enable, or simply run the following command using Wrangler to enable Local Uploads on a bucket.
Ten years ago, we launched our bug bounty program in partnership with HackerOne. Beyond a security initiative, it represented an open invitation to collaborative development.
As pioneers in Southeast Asia, we began the program with 23 initial researchers, and it has since evolved into a global community of security researchers.
The strategic structure and scope of our Bug Bounty Program, combined with our continuous innovation and experimentation, have successfully captured the attention of the global security research community. Over the past decade, we have partnered with more than 850 active security researchers from HackerOne’s community of over 2 million cybersecurity professionals worldwide. These dedicated researchers work alongside us across borders and time zones, forming a collaborative defense network that helps protect over 187 million users throughout Southeast Asia. Their ongoing participation demonstrates both the maturity of our program and the trust we’ve built within the security research community.
This milestone reflects the strength of shared purpose and our sustained partnership with the HackerOne platform. It demonstrates the value of human connection and the collective understanding that security is stronger through collaboration. Here’s to a decade of partnership and to many more years of building a safer future, one collaboration at a time!
Figure 1. Ten years of achievements with our HackerOne partnership.
Evolution and growth: Adapting to a dynamic threat landscape
Over the past ten years, our program has consistently adapted to the dynamic threat landscape and integrated invaluable feedback from our research community. We have grown from a private initiative to a program that consistently ranks among the top 20 worldwide and among the top 3 in Asia on HackerOne. Key milestones from our journey include:
Expanding our horizons: Our scope significantly broadened in 2023-2024, continuously adding new assets and prominently including financial services in Indonesia and AI systems. This expansion provides researchers with more avenues to contribute to Grab’s security.
Focused mobile security: We introduced a dedicated bounty table for mobile-specific issues, recognizing the unique challenges of mobile security.
Incentivizing excellence: We regularly experiment with campaigns of various types and targets, diversifying our reward methods to include both financial rewards and recognition.
Evolving vulnerability focus: We’ve observed a significant shift in the types of vulnerabilities reported over the decade, moving from foundational issues in early years to more sophisticated and emerging categories recently.
Figure 2. The journey of our bug bounty program.
The global stage: Connecting with the best
Our program’s success is deeply rooted in its vibrant global community, which we actively foster through continuous engagement. Our strategy extends beyond the platform to major live hacking events, including the ThreatCon Live Hacking Event 2023in Nepal and DEFCON 32’s Live Recon Village 2024 in Las Vegas. These initiatives have been instrumental in connecting us with a diverse pool of new talent and strengthening relationships with researchers across different continents. By meeting hackers where they are, we’ve not only brought new expertise into our ecosystem but also demonstrated our commitment to being an accessible and collaborative partner on a global scale.
The high participation and quality submissions from these events demonstrate the effectiveness of this approach. They’ve expanded our global security testing coverage and strengthened our standing within the worldwide cybersecurity community. Through ongoing interactions and submitted reports, we continue to see that security is a collaborative effort with no borders.
Exclusive anniversary celebrations: Global club campaigns
To commemorate our 10th anniversary, we launched three exclusive, invite-only campaigns with HackerOne’s regional clubs in Germany, Morocco, and India. These campaigns served as cultural exchanges, bringing fresh perspectives from outside our core Southeast Asian consumer markets. By engaging with these clubs, we expanded our researcher community and connected with security experts who understand different threat landscapes and methodologies, bringing outside perspectives to our systems.
In August, we also ran a broader anniversary campaign that drew significant participation from the researcher community, resulting in 461 submissions. xchopath was awarded the Best Hacker Bonus for their contributions during this campaign.
These campaigns expanded our global security testing coverage and strengthened relationships with international researcher communities. Beyond vulnerability reports, they functioned as knowledge-sharing initiatives. We connected directly with researchers to learn from their experience and feedback, creating a continuous loop of improvement. This international collaboration also informed our global expansion security strategy by providing insights into how different regions approach digital payments and authentication.
The anniversary campaigns allowed us to validate our security frameworks against diverse regulatory environments and advanced testing methodologies from established security markets, reinforcing our commitment to maintaining robust security standards.
Voices from our community
Behind every vulnerability report is a researcher who chose to help make Grab safer. Their perspectives reveal the human side of our security evolution. These individuals are not just cybersecurity experts; they are partners in our mission to protect millions of users and ensure a safe digital environment. Here are a few testimonies from participants in our past campaigns:
“The triage was very fast despite the time difference, which I really appreciated. The triaging experience was better than other programs. The huge scope and business portal with different user roles made it especially interesting to explore.” – ArtSec[H1 Germany club campaign participant]
“I liked that different countries have different features—this gives me more attack surface to explore. Response time was great, triage was very fast, and I appreciated Grab’s effort in providing fast responses. The scope was huge with a lot of wildcards for reconnaissance.” – Sicksec[H1 Morocco club campaign participant]
“More than 20 bugs were reported, and was particularly happy that bounties were being paid upon triage. The Germany team spent a lot of time on the educational part, especially for newcomers. Communication overall was very good, and the immediate response even outside working hours was really cool. SSO and authentication is my expertise and I liked that aspect of exploring the platform.” – Lauritz[H1 Germany club campaign participant]
The road ahead: Our commitment to a secure future
With a strong community of security researchers across countries and a decade of collaboration, we’ve built meaningful partnerships. Every vulnerability report represents trust, and every discovery reflects dedication to our shared mission. The program demonstrates our choice to build together rather than work in isolation, to protect rather than exploit, and to collaborate rather than compete.
While we celebrate our external community, the success of our program relies equally on our dedicated internal teams. Our cybersecurity teams form the operational foundation of this initiative. Their consistent responsiveness and researcher-focused approach have enabled vulnerability reporting to evolve into a genuine partnership, maintaining researcher trust and keeping Grab secure.
The next ten years will bring challenges we can’t yet imagine, from emerging threats in artificial intelligence to novel cryptographic approaches in a quantum-powered world. We will face them together as a community that spans cultures, time zones, and expertise.
Together, we’ll continue securing Southeast Asia’s digital future, one partnership, one discovery, one shared achievement at a time.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
In today’s data-driven landscape, monitoring data quality has become a critical need for ensuring reliable and efficient data usage across domains. High-quality data is the backbone of AI innovation, driving efficiency and unlocking new opportunities. As decentralized data ownership grows, the ability to effectively monitor data quality is essential for maintaining reliability in data systems.
Kafka streams, as a vital component of real-time data processing, play a significant role in this ecosystem. However, unreliable data within Kafka streams can lead to errors and inefficiencies for downstream users, and monitoring the quality of data within these streams has always been a challenge. This blog introduces a solution that empowers stream users to define a data contract, specifying the rules that Kafka stream data must adhere to. By leveraging this user-defined data contract, the solution performs automated real-time data quality checks, identifies problematic data as it occurs, and promptly notifies stream owners. This ensures timely action, enabling effective monitoring and management of Kafka stream data quality while supporting the broader goals of data mesh and AI-driven innovation.
Problem statement
In the past, monitoring Kafka stream data processing lacked an effective solution for data quality validation. This limitation made it challenging to identify bad data, notify users in a timely manner, and prevent the cascading impact on downstream users from further escalating.
Challenges in syntactic and semantic issue identification:
Syntactic issues: Refers to schema mismatches between producers and consumers, which can lead to deserialization errors. While schema backward compatibility can be validated upon schema evolution, there are scenarios where the actual data in the Kafka topic does not align with the defined schema. For example, this can occur when a rogue Kafka producer is not using the expected schema for a given Kafka topic. Identifying the specific fields causing these syntactic issues is a typical challenge.
Semantic issues: Refers to inconsistencies or misalignments between producers and consumers about the expected pattern or significance of each field. Unlike Kafka stream schemas, which act as a data structure contract between producers and consumers, there is no existing framework for stakeholders to define and enforce field-level semantic rules, for example, the expected length or pattern of an identifier.
Timeliness challenge in data quality monitoring: There is no real-time mechanism to automatically validate data against predefined rules, timely identify quality issues, and promptly alert stream stakeholders. Without real-time stream validation, data quality issues can sometimes persist for periods of time, impacting various online and offline downstream systems before being discovered.
Observability challenge for troubleshooting bad data: Even when problematic data is identified, stream users face difficulties in pinpointing the exact “poison data” and understanding which fields are incompatible with the schema or violate semantic rules. This lack of visibility complicates Root Cause Analysis and resolution efforts.
Solution
Our Coban platform offers a standardized data quality test and observability solution at the platform level, consisting of the following components:
Data Contract Definition: Enables Kafka stream stakeholders to define contracts that include schema agreements, semantic rules that Kafka topic data must comply with, and Kafka stream ownership details for alerting and notifications.
Automated Test Execution: Provides a long running Test Runner to automatically execute real-time tests based on the defined contract.
Real-time Data Quality Issue Identification: Detects data issues at both syntactic and semantic levels in real-time.
Alerts and Result Observability: Alerts users, simplifying observation of data quality issues via the platform.
Architecture details
The solution includes three components: Data Contract Definition, Test Execution & Data Quality Issue Identification, and Result Observability as shown in the architecture diagram in figure 1. All mentions of “Flow” from here onwards refer to the corresponding processes illustrated in figure 1.
Figure 1. Real-time Kafka Stream Data Quality Monitoring Architecture diagram.
Data Contract Definition
The Coban Platform streamlines the process of defining Kafka stream data contracts, serving as a formal agreement among Kafka stream stakeholders. This includes the following components:
Kafka Stream Schema: Represents the schema used by the Kafka topic under test and helps the Test Runner to validate schema compatibility across data streams (Flow 1.1).
Kafka Stream Configuration: Encompasses essential configurations such as the endpoint and topic name, which the platform automatically populates (Flow 1.2).
Observability Metadata: Provides contact information for notifying Kafka stream stakeholders about data quality issues and includes alert configurations for monitoring (Flow 1.3).
Kafka Stream Semantic Test Rules: Empowers users to define intuitive semantic test rules at the field level. These rules include checks for string patterns, number ranges, constant values, etc. (Flow 1.5).
LLM-Based Semantic Test Rules Recommendation: Defining dozens if not hundreds of field-specific test rules can overwhelm users. To simplify this process, the Coban Platform uses LLM-based recommendations to predict semantic test rules using provided Kafka stream schemas and anonymized sample data (Flow 1.4). This feature helps users set up semantic rules efficiently, as demonstrated in the sample UI in figure 2.
Figure 2. Sample UI showcasing LLM-based Kafka stream schema field-level semantic test rules. Note that the data shown is entirely fictional.
Data Contract Transformation
Once defined, the Coban Platform’s transformation engine converts the data contract into configurations that the Test Runner can interpret (Flow 2.1). This transformation process includes:
Kafka Stream Schema: Translates the schema defined in the data contract into a schema reference that the Test Runner can parse.
Kafka Stream Configuration: Sets up the Kafka stream as a source for the Test Runner.
Observability metadata: Sets contact information as configurations of the Test Runner.
Kafka Stream Semantic Test Rules: Transforms human-readable semantic test rules into an inverse SQL query to capture the data that violates the defined rules.
Figure 3. Illustration of semantic test rules being converted from human-readable formats into inverse SQL queries.
Test Execution & Data Quality Issue Identification
Once the Test Configuration Transformation Engine generates the Test Runner configuration (Flow 2.1), the platform automatically deploys the Test Runner.
Test Runner
The Test Runner utilises FlinkSQL as the compute engine to execute the tests. FlinkSQL was selected for its flexibility in defining test rules as straightforward SQL statements, enabling our platform to efficiently convert data contracts into enforceable rules.
Test Execution Workflow And Problematic Data Identification
FlinkSQL consumes data from the Kafka topic under test (Flow 2.2) using its own consumer group, ensuring it doesn’t impact other consumers. It runs the inverse SQL query (Flow 2.3) to identify any data that violates the semantic rules or that is syntactically incorrect in the first place. Test Runner captures such data, packages it into a data quality issue event enriched with a test summary, the total count of bad records, and sample bad data, and publishes it to a dedicated Kafka topic (Flow 3.2). Additionally, the platform sinks all such data quality events to an AWS S3 bucket (Flow 3.1) to enable deeper observability and analysis.
Result Observability
Grab’s in-house data quality observability platform, Genchi, consumes problematic data captured by the Test Runner (Flow 3.3).
Alerting
Genchi sends Slack notifications (Flow 3.5) to stream owners specified in the data contract observability metadata. These notifications include detailed information about stream issues, such as links to sample data in Coban UI, observed windows, counts of bad records, and other relevant details.
Figure 4. Sample Slack notifications
Observability
Users can access the Coban UI (Flow 3.4), displaying Kafka stream test rules and sample bad records, highlighting fields and values that violate rules.
Figure 5. In this Sample Test Result, the highlighted fields indicate violations of the semantic test rules.
Impact
Since its deployment earlier this year, the solution has enabled Kafka stream users to define contracts with syntactic and semantic rules, automate test execution, and alert users when problematic data is detected, prompting timely action. It has been actively monitoring data quality across 100+ critical Kafka topics. The solution offers the capability to immediately identify and halt the propagation of invalid data across multiple streams.
Conclusion
We implemented and rolled out a solution to assist Grab engineers in effectively monitoring data quality in their Kafka streams. This solution empowers them to establish syntactic and semantic tests for their data. Our platform’s automatic testing feature enables real-time tracking of data quality, with instant alerts for any discrepancies. Additionally, we provide detailed visibility into test results, facilitating the easy identification of specific data fields that violate the rules. This accelerates the process of diagnosing and resolving issues, allowing users to swiftly address production data challenges.
What’s next
While our current solution emphasizes monitoring the quality of Kafka streaming data, further exploration will focus on tracing producers to pinpoint the origin of problematic data, as well as enabling more advanced semantic tests such as cross-field validations. Additionally, we aim to expand monitoring capabilities to cover broader aspects like data completeness and freshness, and integrate with Gable AI to detect Data Transfer Object (DTO) changes and semantic regressions in Go producers upon committing code to the Git repository. These enhancements will pave the way for a more robust, multidimensional data quality testing solution across a wider range.
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
At Grab, innovation isn’t just about building new features; it’s about evolving our platforms to meet the changing needs of our users and the broader technological landscape. SpellVault, our internal AI platform, exemplifies this philosophy. When SpellVault was first launched, our vision was straightforward: empower everyone at Grab to effortlessly build and manage AI-powered apps without the need for coding. Built on the principles of Retrieval-Augmented Generation (RAG) and enhanced by plugin support, SpellVault rapidly evolved into a powerful productivity engine for the organization, enabling the creation of thousands of apps that drive automation, foster experimentation, and support production use cases.
As the AI landscape has evolved, SpellVault has grown alongside it. Initially launched as a straightforward no-code app builder for Large Language Models (LLMs), it has now evolved into a cutting-edge platform that embraces the agentic future—a future where AI goes beyond generating responses to reasoning, acting, and dynamically adapting through the use of tools and contextual understanding.
This article outlines SpellVault’s journey towards an agentic future and how we empower users to build AI Agents that are smarter, more adaptable, and ready for the future.
A no-code platform for building LLM apps
SpellVault was founded with a clear mission: to democratize access to AI for everyone at Grab, regardless of their technical expertise. Initially launched as a no-code LLM app builder, the platform was built on a foundation of RAG pipelines and basic plugin support.
Early on, we recognized that the true potential of AI apps extends beyond the capabilities of language models alone. Their real value lies in the ability to seamlessly interact with external systems and diverse data sources. This insight drove our commitment to minimizing barriers and ensuring users could access data from various sources with ease. From the very beginning, we centered our efforts on three key focus areas:
Comprehensive RAG solution with useful integrations
From the start, the SpellVault team prioritized enabling users to enhance their LLM apps with data through RAG. Rather than solely relying on the LLM’s internal information, we wanted the apps to ground their responses in up-to-date, contextually relevant, and factual information. SpellVault has built-in integrations with knowledge sources such as Wikis, Google Docs, as well as plain text and PDF uploads. These capabilities empower users to build assistants that reference relevant knowledge and provide more accurate, verifiable answers.
Plugins to fetch information on demand
To move beyond static knowledge retrieval, we needed a way for apps to act dynamically. This was made possible through SpellVault plugins—modular components that allow apps to interact with internal systems (e.g. service dashboards, incident trackers) and external APIs (e.g. search engines, weather data). Rather than being confined to their initial prompt and data, these plugins can fetch fresh information at runtime. From the available plugin types, users can create their own instances of plugins with custom settings, enabling highly specialized functionality tailored to their specific workflows. For instance, with SpellVault’s HTTP plugin, users can define custom endpoints and credentials, enabling their AI apps to make tailored HTTP calls during runtime. These custom plugins have become the backbone of many of our most impactful apps, empowering teams to seamlessly integrate SpellVault with their existing systems and processes.
Figure 1. SpellVault’s early architecture.
Making SpellVault accessible via common interfaces: Web, Slack, API
One of our primary goals was to make AI seamlessly accessible and useful within the tools users already use—whether it’s a browser or Slack. With SpellVault, users can make their AI apps in minutes and start using them via browser or Slack messaging immediately and intuitively, without requiring any additional setup. We also exposed APIs that enabled other internal services to integrate with SpellVault apps for a variety of use cases. This multi-channel approach ensured that SpellVault wasn’t just a standalone sandbox but a platform woven into existing tools and processes.
Users quickly adopted the platform, creating thousands of apps for internal productivity gains, automation, and even production use cases. The platform’s success validated our hypothesis that there was significant demand for democratized AI tools within the organization.
Figure 2. SpellVault’s web interface for LLM App configuration and chat.
Evolution over time
The AI landscape over the past few years has been defined by relentless change. New frameworks, execution paradigms, and standards have emerged in quick succession, each promising to make AI systems more powerful, more reliable, or more extensible. At Grab, we recognized that for SpellVault to stay relevant, it could not remain static. It needed to evolve in tandem with the ever-changing ecosystem, continuously incorporating valuable advancements while ensuring a seamless experience for our users.
This philosophy of continuous adaptation has guided SpellVault’s journey. From its early days as a simple RAG-powered app builder with a few plugins, the platform grew to support an extensive number of plugin types, richer execution models, and eventually a unified approach to tools. Each step was a response both to the needs of our users and to the shifting definition of what “building with AI” meant in practice. Rather than opting for a complete overhaul, SpellVault has embraced incremental advancements, ensuring that users can seamlessly benefit from new capabilities without disruption.
This approach to evolution has naturally positioned SpellVault to transition from a platform for LLM apps to one designed for AI agents. The following section delves into this transition in greater detail.
Expanding capabilities
Over time, we introduced numerous new capabilities to SpellVault, driven both by user feedback and our commitment to innovation and staying ahead of industry trends. For instance, we extended support for different plugin types, enabling integrations with tools like Slack and Kibana, and continuously added more integrations to enhance the platform’s versatility. We implemented auto-updates for users’ Knowledge Vaults, ensuring their data remained current. With more users building with the platform, ensuring the trustworthiness of responses generated by SpellVault apps became increasingly important. We included citation capability to mitigate some of that concern. Recognizing the need for more precise answers to mathematical problems, we developed a feature that enabled LLMs to solve such problems using Python runtime. Additionally, many users requested an automated way to trigger their LLM apps, which led to the creation of a Task Scheduler feature that allows LLMs to schedule actions based on natural language user input.
A significant milestone in SpellVault’s evolution was the introduction of “Workflow,” a drag-and-drop interface within the platform that empowered users to design deterministic workflows. These workflows enabled users to seamlessly combine various components from the SpellVault ecosystem—such as LLM calls, Python code execution, and Knowledge Vault lookups—in a predefined and structured manner. This enabled advanced use cases for many users.
Figure 3. Evolving tools landscape of SpellVault with increasing integrations.
Shifting the execution model
As SpellVault evolved, a fundamental shift took place in the way its apps were executed internally. We transitioned from our legacy executor system, which facilitated one-off information retrieval from the Knowledge Vault or user plugins, to a more advanced graph based executor. This empowered SpellVault’s app execution with nodes, edges, and states that supported branching, looping, and modularity. This laid the groundwork for more sophisticated agent behaviors, moving beyond the linear input-output paradigm.
This transformed all existing SpellVault apps into ‘Reasoning and Acting’ agents, better known as ReAct agents – a “one size fits many” solution that significantly enhanced the capabilities of these apps. By enabling them to leverage the Knowledge Vault and plugins in a more agentic and dynamic manner, the ReAct agent framework allowed apps to perform more complex tasks while seamlessly preserving their existing functionality, ensuring no disruption to their behavior.
In addition, the internal decoupling of the executor and prompt engineering components enabled us to design multiple execution pathways with ease. This allowed us to provide generic Deep Research capability to any SpellVault app via a simple UI checkbox, as well as sophisticated internal workflows that cater to high-ROI complex use cases like on-call alert analysis. The Deep Research capability came with SpellVault’s ability to search across internal information repositories (e.g., Slack messages, Wiki, Jira) within Grab, as well as searching online for relevant information.
Figure 4. SpellVault’s evolved architecture with more dynamic context gathering and advanced interaction modes.
Towards an agentic framework
Over time, several capabilities were added to SpellVault, including features like Python code execution and internal repository search. Initially, these functionalities were integrated directly into the core PromptBuilder class. For users, these features were primarily accessible through simple checkboxes in the user interface. As SpellVault gradually transitioned towards giving more agency to user-crafted apps, we recognized that these capabilities should instead be positioned as “Tools” for LLMs to use with greater autonomy, similar to how ReAct agent–backed apps have been using SpellVault’s user plugins. We also understood that this shift could bring a clearer mental model for users where they were no longer simply toggling features but creating AI agents with access to a defined set of tools. The agents could then decide when and how to use those tools intelligently to accomplish tasks, making the overall experience more natural and intuitive.
This recognition led to the consolidation of these scattered capabilities into a unified framework called “Native Tools.” These Native Tools, along with SpellVault’s existing user plugins—rebranded as “Community Built Tools”—formed a comprehensive collection of tools that LLMs could dynamically invoke at runtime. Despite being grouped under the same umbrella, a key distinction was maintained: Native Tools required no user-specific configuration (e.g., performing internet searches), whereas Community Built Tools were custom, user-configured entities (e.g., invoking specific HTTP endpoints) created from available plugin types, often requiring credentials or other personalized settings.
This consolidation of capabilities under a unified Tools abstraction and enabling SpellVault apps to invoke them with greater autonomy marked a pivotal milestone in the platform’s evolution. It meaningfully shifted SpellVault toward making agentic behavior more natural, discoverable, and extensible for every app.
Figure 5. SpellVault’s Unified Tools housing both Native Tools and Community Built Tools.
SpellVault as an MCP service
As we streamlined SpellVault’s internal capabilities into a unified tools framework, we also turned our focus outward to align with industry standards. The growing adoption of the Model Context Protocol (MCP) presented an opportunity for agents and clients to seamlessly interact without requiring custom integrations. To remain at the forefront of innovation, we adapted SpellVault to function as an MCP service, enabling it to actively participate in this evolving ecosystem. This extension brought two key advancements:
SpellVault apps as MCP tools: Each app created in SpellVault can now be exposed through the MCP protocol. This allows other agents or MCP-compatible clients, such as IDEs or external orchestration frameworks, to treat a SpellVault app as a callable tool. Instead of living only inside our web user interface or Slack interface, these apps become accessible building blocks that other systems can invoke dynamically.
RAG as an MCP tool: We extended the same idea to our Knowledge Vaults. Through MCP, external clients can search, retrieve, and even add information to Vaults. This effectively turns SpellVault’s RAG pipeline into an MCP-native service, making contextual grounding available to agents beyond SpellVault itself.
While building the SpellVault MCP Server, we also created TinyMCP – a lightweight open-source Python library that adds MCP capabilities to an existing FastAPI app as just another router, instead of mounting a separate app.
By exposing both apps and RAG through MCP, we shifted SpellVault from being a self-contained platform to becoming an interoperable service provider in the agentic ecosystem. Users still benefit from the no-code simplicity inside SpellVault. However, the output of their work, apps, and knowledge, are now usable by other agents and tools outside of it.
Conclusion
SpellVault’s evolution shows how a platform can adapt with the AI landscape while staying true to its original mission of making powerful technology accessible to everyone. What began as a no-code builder for LLM apps has steadily expanded into an agentic platform – one where apps can act with more intelligence, agency, and context and interact with the systems around them.
This progress wasn’t the result of a single breakthrough, but of steady, incremental improvements that introduced new capabilities while preserving ease of use. By layering in these advancements thoughtfully but boldly, SpellVault has managed to support more sophisticated agentic behaviors without compromising its original goal of democratizing AI at Grab.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.