Enterprise scale in-place migration to Apache Iceberg: Implementation guide

Post Syndicated from Mihir Borkar original https://aws.amazon.com/blogs/big-data/enterprise-scale-in-place-migration-to-apache-iceberg-implementation-guide/

Organizations managing large-scale analytical workloads increasingly face challenges with traditional Apache Parquet-based data lakes with Hive-style partitioning, including slow queries, complex file management, and limited consistency guarantees. Apache Iceberg addresses these pain points by providing ACID transactions, seamless schema evolution, and point-in-time data recovery capabilities that transform how enterprises handle their data infrastructure.

In this post, we demonstrate how you can achieve migration at scale from existing Parquet tables to Apache Iceberg tables. Using Amazon DynamoDB as a central orchestration mechanism, we show how you can implement in-place migrations that are highly configurable, repeatable, and fault-tolerant—unlocking the full potential of modern data lake architectures without extensive data movement or duplication.

Solution overview

When performing in-place migration, Apache Iceberg uses its ability to directly reference existing data files. This capability is only supported for formats such as Parquet, ORC, and Avro, because these formats are self-describing and include consistent schema and metadata information. Unlike raw formats such as CSV or JSON, they enforce structure and support efficient columnar or row-based access, which allows Iceberg to integrate them without rewriting the data.

In this post, we demonstrate how you can migrate an existing Parquet-based data lake that isn’t cataloged in AWS Glue by using two methodologies:

  • Apache Iceberg migrate and register_table approach. Ideal for converting existing Hive-registered Parquet tables into Iceberg-managed tables.
  • Iceberg add_files approach. Best suited for quickly onboarding raw Parquet data into Iceberg without rewriting files.

The solution also incorporates a DynamoDB table that acts as a scalable control plane, so you can perform in-place migration of your data lake from Parquet format to Iceberg format.

The following diagram shows different methodologies that you can use to achieve this in-place migration of your Hive-style partitioned data lake:
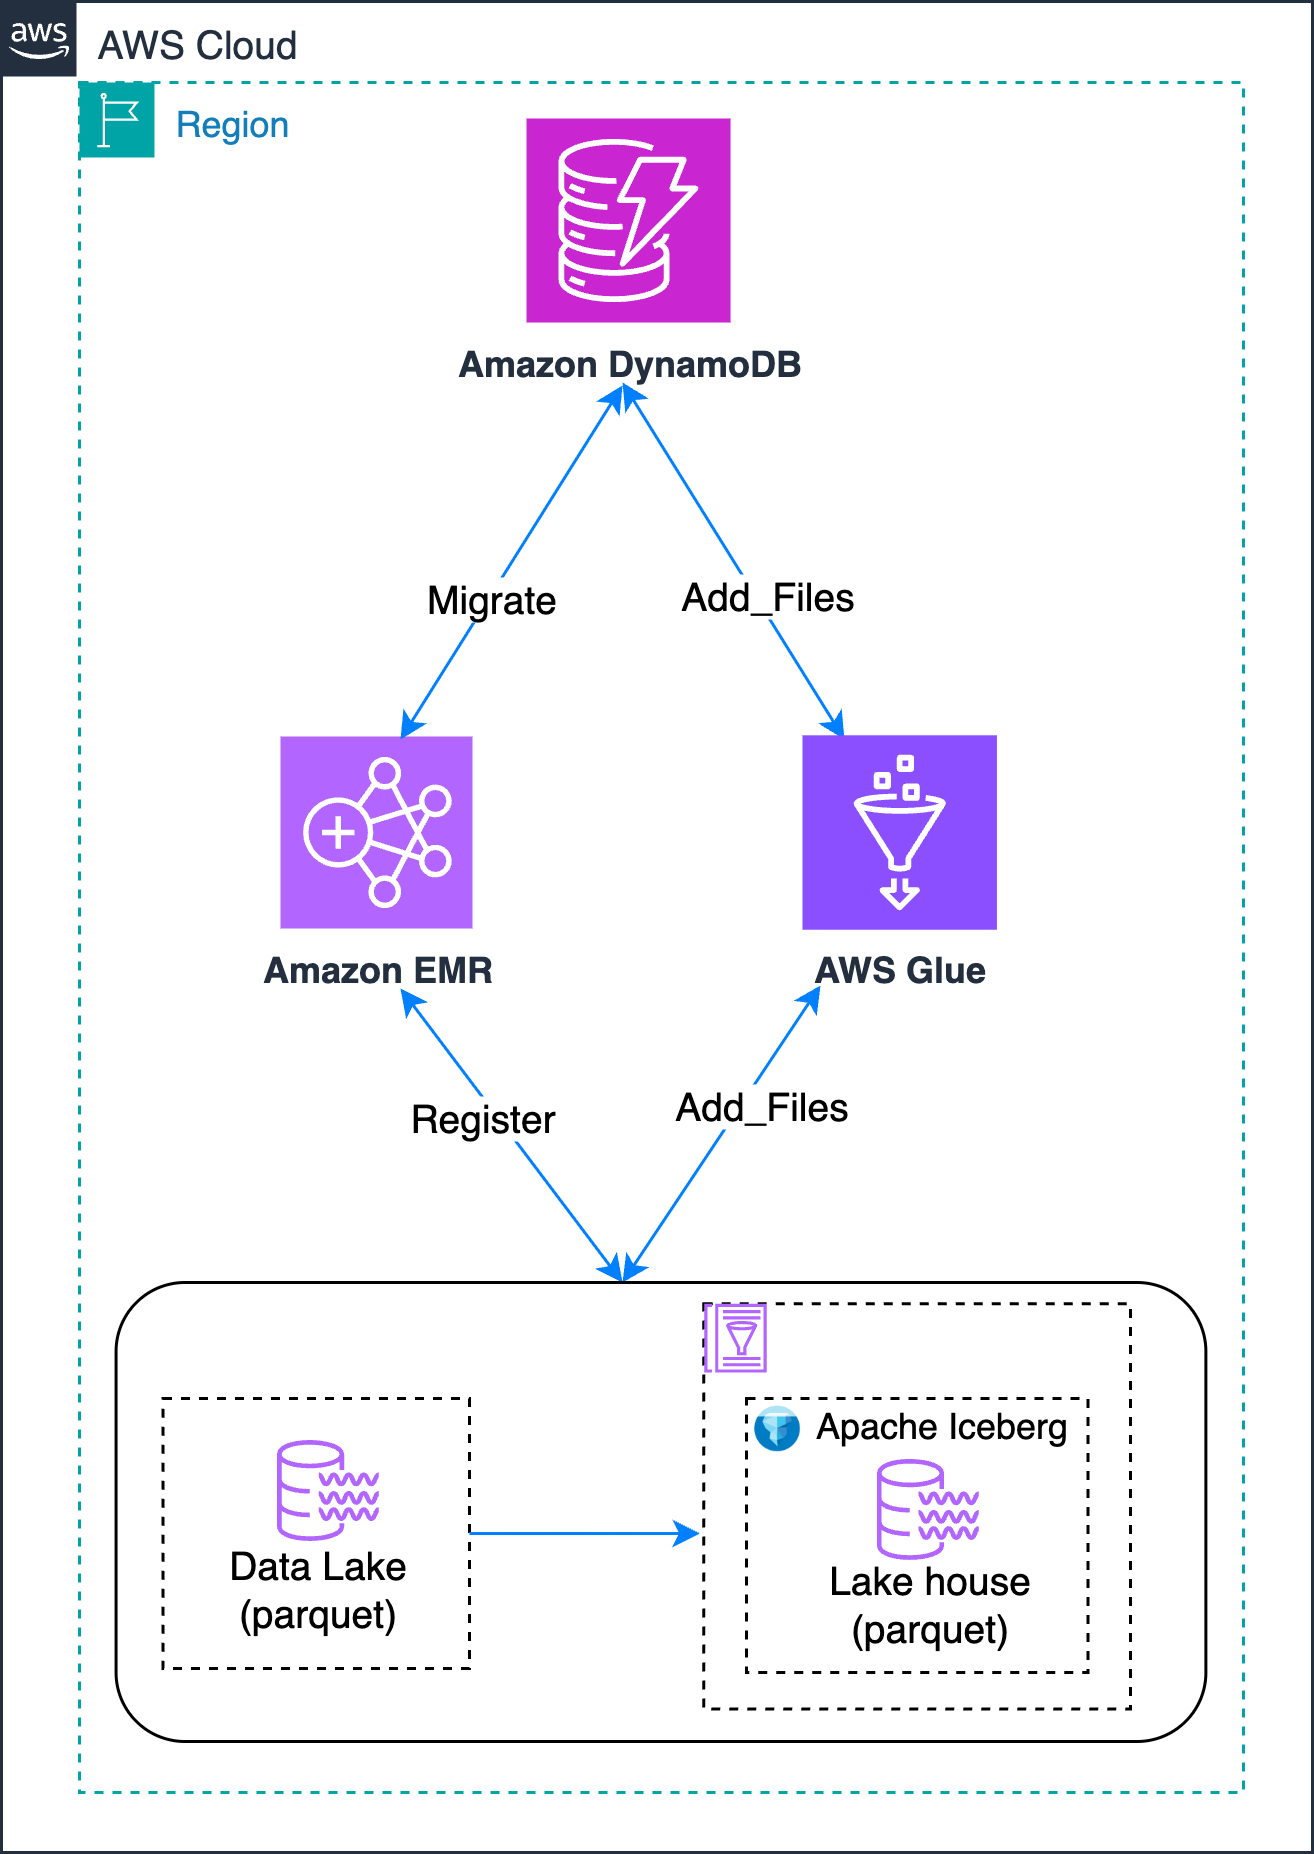
AWS data pipeline architecture diagram showing data flow from Amazon DynamoDB through Amazon EMR and AWS Glue to a Data Lake and Apache Iceberg Lakehouse, both using Parquet format, within an AWS Region.

You use DynamoDB to track the migration state, handling retries and recording errors and outcomes. This provides the following benefits:

  • Centralized control over which Amazon Simple Storage Service (Amazon S3) paths need migration.
  • Lifecycle tracking of each dataset through migration stages.
  • Capture and audit errors on a per-path basis.
  • Enable re-runs by updating stateful flags or clearing failure messages.

Prerequisites

Before you begin, you need:

Create sample Parquet dataset as a source

You can create the sample Parquet dataset for testing the different methodologies using the Athena query editor. Replace <amzn-s3-demo-bucket> with an available bucket in your account.

  1. Create an AWS Glue database(test_db), if not present.
    CREATE DATABASE IF NOT EXISTS test_db

  2. Create a sample Parquet table (table1) and add to be used for testing the add_files approach.
    CREATE TABLE table1
    WITH (
      external_location = 's3://<amzn-s3-demo-bucket>/table1/',
      format = 'PARQUET',
      partitioned_by = ARRAY['date', 'hour']
    )
    AS
    SELECT 
      1 as id,
      'John Doe' as name,
      25 as age,
      'Engineer' as job_title,
      current_date as created_date,
      current_date as date,
      hour(current_timestamp) as hour
    UNION ALL
    SELECT 2, 'Jane Smith', 30, 'Manager', current_date, current_date, hour(current_timestamp)
    UNION ALL  
    SELECT 3, 'Bob Johnson', 35, 'Analyst', current_date, current_date, hour(current_timestamp);

  3. Create a sample Parquet table (table2) and add data to be used for testing the migrate and register_table approach. Replace <amzn-s3-demo-bucket> with your bucket name.
    CREATE TABLE table2
    WITH (
      external_location = 's3://<amzn-s3-demo-bucket>/table2/',
      format = 'PARQUET',
      partitioned_by = ARRAY['date', 'hour']
    )
    AS
    SELECT 
      1 as id,
      'John Doe' as name,
      25 as age,
      'Engineer' as job_title,
      current_date as created_date,
      current_date as date,
      hour(current_timestamp) as hour
    UNION ALL
    SELECT 2, 'Jane Smith', 30, 'Manager', current_date, current_date, hour(current_timestamp)
    UNION ALL  
    SELECT 3, 'Bob Johnson', 35, 'Analyst', current_date, current_date, hour(current_timestamp);

  4. Drop the tables from the Data Catalog because you only need Parquet data with the Hive-style partitioning structure.
    DROP TABLE IF EXISTS test_db.table1

Create a DynamoDB control table

Before beginning the migration process, you must create a DynamoDB table that serves as the control plane. This table maps source Amazon S3 paths to their corresponding Iceberg database and table destinations, enabling systematic tracking of the migration process.

To implement this control mechanism, create a table with the following structure:

  • A primary key s3_path that stores the source Parquet data location
  • Two attributes that define the target Iceberg location:
    • target_db_name
    • target_table_name

To create the DynamoDB control table

  1. Create the Amazon DynamoDB table using the following AWS CLI command:
    aws dynamodb create-table \
    --table-name migration-control-table \
    --attribute-definitions \
    AttributeName=s3_path,AttributeType=S \
    --key-schema \
    AttributeName=s3_path,KeyType=HASH \
    --billing-mode PAY_PER_REQUEST \
    --region <REGION>

  2. Verify the table is created successfully. Replace <REGION> with the AWS Region where your data is stored:
    aws dynamodb describe-table --table-name migration-control-table --region <REGION>

  3. Create a migration_data.json file with the following contents.
    In this example:

    • Replace <amzn-s3-demo-bucket> and <TablePrefix>with the name of your S3 bucket and prefix containing the Parquet data
    • Replace <DatabaseName> with the name of your target Iceberg database
    • Replace <TableName> with the name of your target Iceberg table
    {
        "your-migration-table": [
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/table1/"},
                        "target_db_name": {"S": "test_db"},
                        "target_table_name": {"S": "table1"}
                    }
                }
            },
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/table2/"},
                        "target_db_name": {"S": "test_db"},
                        "target_table_name": {"S": "table2"}
                    }
                }
            },
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/<TablePrefix>/"},
                        "target_db_name": {"S": "<DatabaseName>"},
                        "target_table_name": {"S": "<TableName>"}
                    }
                }
            }
        ]
    }

    This file defines the mapping between Amazon S3 paths and their corresponding Iceberg table destinations.

  4. Run the following CLI command to load the DynamoDB control table.
    aws dynamodb batch-write-item \
    --request-items file://migration_data.json \
    --region <REGION;>

Migration methodologies

In this section, you explore two methodologies for migrating your existing Parquet tables to Apache Iceberg format:

  • Apache Iceberg migrate and register_table approach – This approach first converts your Parquet table to Iceberg format using the native migrate procedure, followed by registering it in AWS Glue using the register_table procedure.
  • Apache Iceberg add_files approach – This method creates an empty Iceberg table and uses the add_files procedure to import existing Parquet data files without physically moving them.

Apache Iceberg migrate and register_table procedure

Use the Apache Iceberg Migrate procedure that is used for in-place conversion of an existing Hive or Parquet table into an Iceberg-managed table. Thereafter, you can use the Apache Iceberg RegisterTable procedure to register the respective table in AWS Glue.
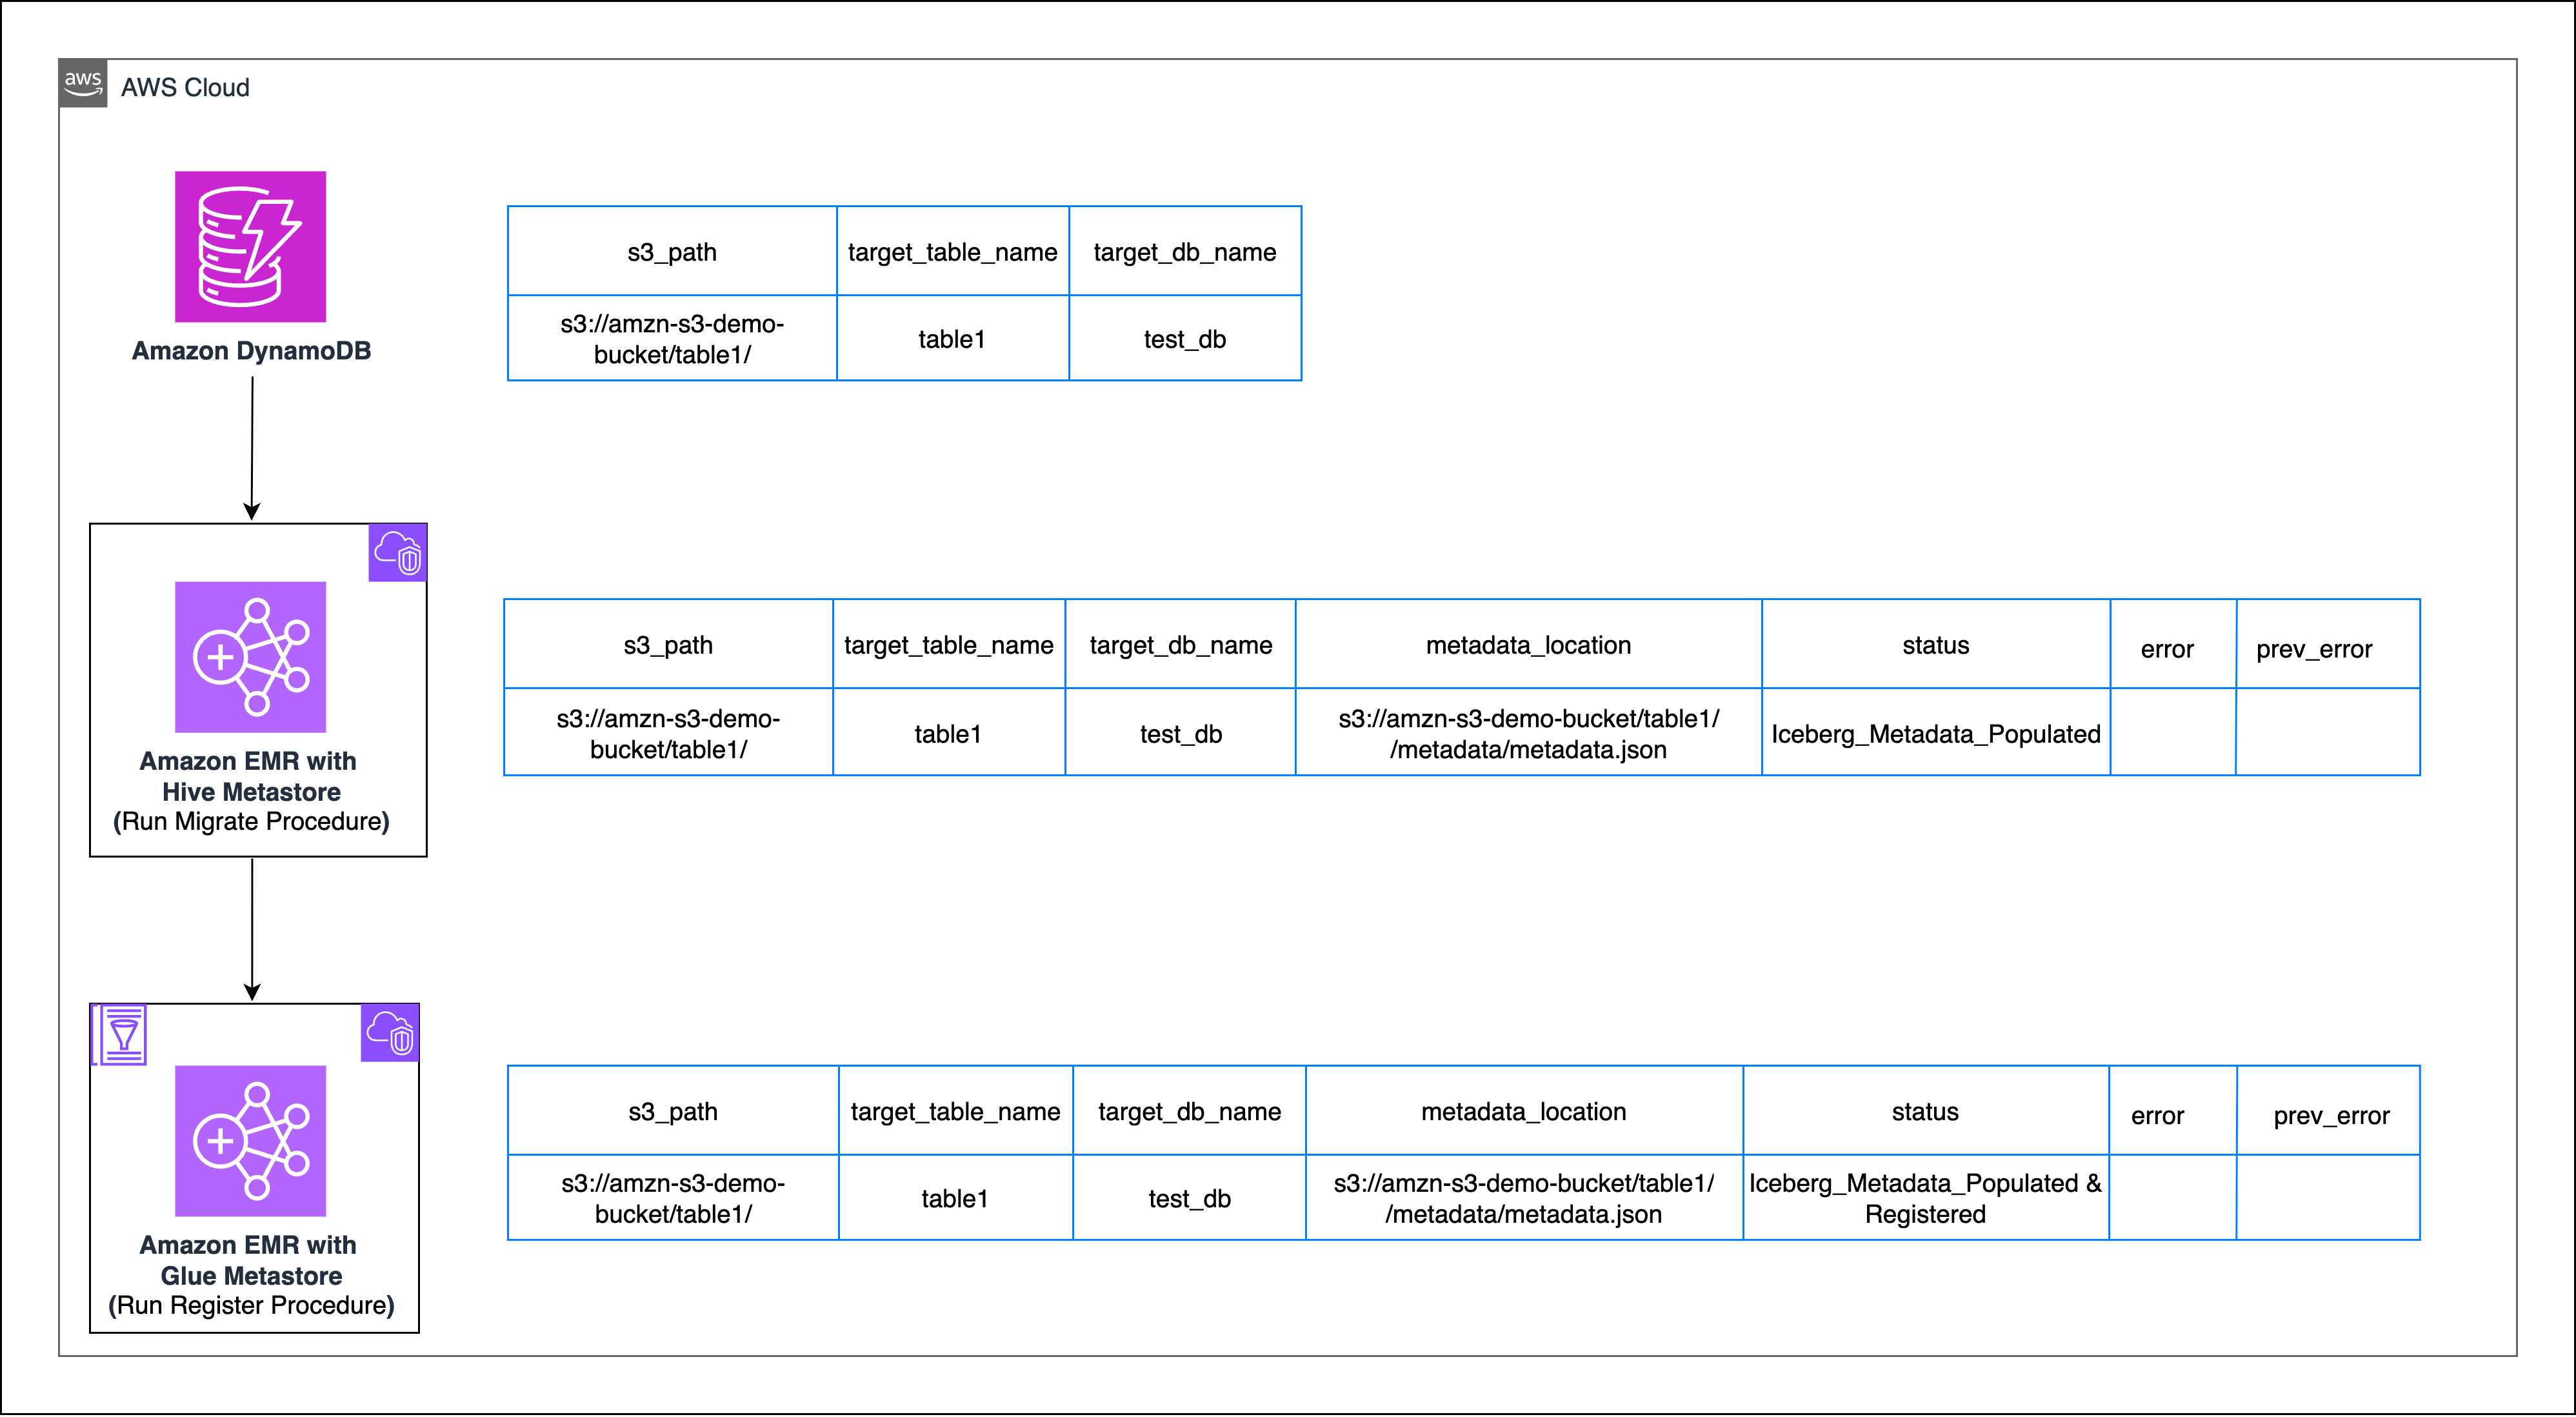
AWS workflow diagram showing DynamoDB to Apache Iceberg migration using Amazon EMR with Hive Metastore for migration and Glue Metastore for registration, displaying configuration tables at each stage.

Migrate

  1. In your EMR cluster with Hive as the metastore, create a PySpark session with the following Iceberg Packages:
    pyspark \
    --name "Iceberg Migration" \
    --conf "spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar" \
    --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
    --conf spark.sql.catalog.spark_catalog=org.apache.iceberg.spark.SparkSessionCatalog \
    --conf spark.sql.catalog.spark_catalog.type=hive

    This post uses Iceberg v1.9.1 (Amazon EMR build), which is native to Amazon EMR 7.11. Always verify the latest supported version and update package coordinates accordingly.

  2. Next, create your corresponding table in your Hive catalog (you can skip this step if you already have tables created in your hive catalog). Replace <amzn-s3-demo-bucket> with the name of your S3 bucket.
    In the following snippet, change or remove the PARTITIONED BY command based on the partition strategy of your table, the MSCK Repair table command should only be run if your respective table is partitioned.

    #You can automate this for production Scaling with DynamoDB as control table 
    s3_path = "s3://<amzn-s3-demo-bucket>/table1/"
    target_db_name = "test_db"
    target_table_name = "table1"
    # Read data in a dataframe to infer schema
    df = spark.read.parquet(s3_path)
    df.createOrReplaceTempView("temp_view")
    # Get schema as string
    schema = spark.table("temp_view").schema
    schema_string = ", ".join([f"{field.name} {field.dataType.simpleString()}" for field in schema])
    # Create Database If not exists 
    spark.sql(f"CREATE DATABASE IF NOT EXISTS {target_db_name}").show()
    # full_table_name= test_db.table1
    full_table_name = f"{target_db_name}.{target_table_name}"
    # Create table
    spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {full_table_name} (
        {schema_string}
    )
    STORED AS PARQUET
    PARTITIONED BY (date, hour)
    LOCATION '{s3_path}'
    """)
    # Refresh, repair, and validate
    spark.sql(f"REFRESH TABLE {full_table_name}")
    spark.sql(f"MSCK REPAIR TABLE {full_table_name}")

  3. Convert the Parquet table to an Iceberg table in Hive
    # Run migration procedure
    spark.sql(f"CALL spark_catalog.system.migrate('{full_table_name}')")
    # Validate that the table is successfully migrated 
    spark.sql(f"DESCRIBE FORMATTED {full_table_name}").show(truncate=False)

Run the migrate command to convert the Parquet-based table to an Iceberg table, creating the metadata folder and the metadata.json file therein

You can stop at this point if you don’t intend to migrate your existing iceberg table from Hive to the Data Catalog.

Register

  1. Sign in to the AWS Glue as Spark Catalog enabled EMR cluster.
  2. Register the Iceberg table to your Data Catalog.

    Create the session with the respective Iceberg Packages. Replace <amzn-s3-demo-bucket> with your bucket name, and <warehouse> with warehouse directory.

    pyspark \
    --conf "spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar" \
    --conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
    --conf "spark.sql.catalog.glue_catalog=org.apache.iceberg.spark.SparkCatalog" \
    --conf "spark.sql.catalog.glue_catalog.warehouse= s3://<amzn-s3-demo-bucket>/<warehouse>/"  \
    --conf "spark.sql.catalog.glue_catalog.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog" \
    --conf "spark.sql.catalog.glue_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO"

  3. Run the register_table command to make the Iceberg table visible in AWS Glue.
    • register_table registers an existing Iceberg table’s metadata file (metadata.json) with a catalog(glue_catalog) so that Spark (and other engines) can query it.
    • The procedure creates a Data Catalog entry for the table, pointing it to the given metadata location.

    Replace <amzn-s3-demo-bucket> and <metadata-prefix> with the name of your S3 bucket and metadata prefix name.

    Ensure that your EMR Spark Cluster has been configured with appropriate AWS Glue permissions

    # You can automate this for production Scaling with DynamoDB as control table
    metadata_location = "s3://<amzn-s3-demo-bucket>/table1/metadata/<metadata-prefix>.metadata.json"
    target_db_name = "test_db"
    target_table_name = "table1"
    full_table_name = f"{target_db_name}.{target_table_name}"
    # Register existing Iceberg table metadata in Glue Catalog
    spark.sql(f"CALL glue_catalog.system.register_table('{full_table_name}', '{metadata_location}')")
    # Set table properties (example: Iceberg format version 2)
    spark.sql(f"ALTER TABLE glue_catalog.{full_table_name} SET TBLPROPERTIES('format-version'='2')")

  4. Validate that the Iceberg table is now visible in the Data Catalog.
    # Lookout for format as iceberg/parquet
    spark.sql("SHOW TBLPROPERTIES glue_catalog.test_db.table1").show()

Apache Iceberg’s add_files procedure

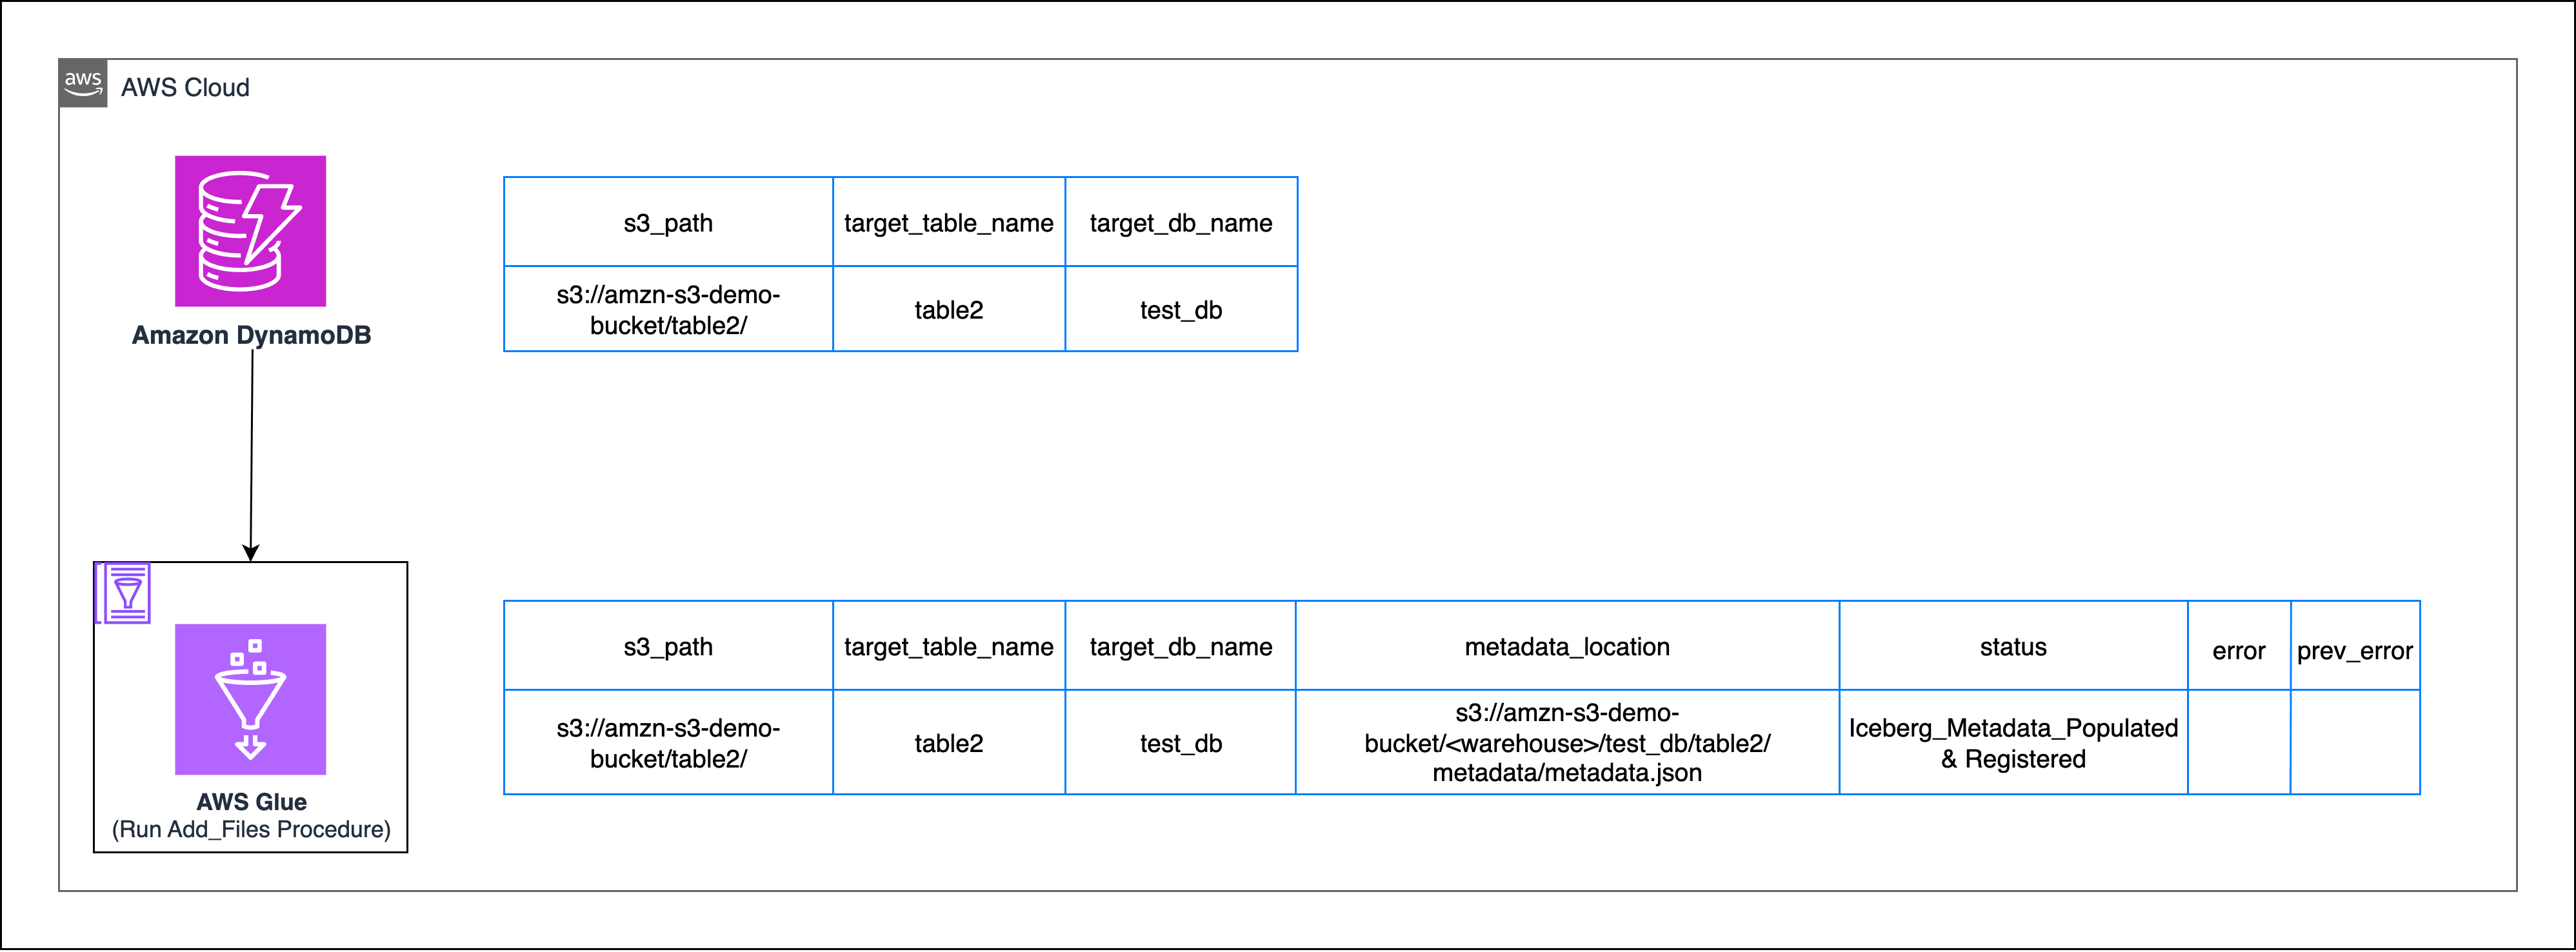
AWS workflow diagram showing DynamoDB to Apache Iceberg migration using AWS Glue Add_Files procedure, displaying input configuration and output status tables with metadata location and registration confirmation.

Here, you’re going to use Iceberg’s add_files procedure to import raw data files (Parquet, ORC, Avro) into an existing Iceberg table by updating its metadata. This procedure works for both Hive and Data Catalog, it doesn’t physically move or rewrite the files—it only registers them so Iceberg can manage them.

This methodology comprises the following steps:

  1. Create an empty Iceberg table in AWS Glue.
    Because the add_files procedure expects the iceberg table to be already present, you need to create an empty Iceberg table by inferring the table schema.
  2. Register existing data locations to the Iceberg table

Using the add_files procedure in a Glue-backed Iceberg catalog will register the target S3 path along with all its subdirectories to the empty Iceberg table created in the previous step.

You can consolidate both steps into a single Spark job. For the following AWS Glue job, you have specified iceberg as a value for the --datalake-formats job parameter. See the AWS Glue job configuration documentation for more details.

Replace <amzn-s3-demo-bucket> with your S3 bucket name and <warehouse> with warehouse directory.

from pyspark.sql import SparkSession
import logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)
target_db_name = "test_db"
target_table_name = "table2"
s3_path = "s3://<amzn-s3-demo-bucket>/table2"
# Set to None or [] for unpartitioned
partitioned_cols = ["date", "hour"]  
spark = SparkSession.builder \
    .appName("Iceberg Add Files") \
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions") \
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog") \
    .config("spark.sql.catalog.glue_catalog.catalog-impl", "org.apache.iceberg.aws.glue.GlueCatalog") \
    .config("spark.sql.catalog.glue_catalog.io-impl", "org.apache.iceberg.aws.s3.S3FileIO") \
    .config("spark.sql.catalog.glue_catalog.warehouse", "s3://<amzn-s3-demo-bucket>/<warehouse>/") \
    .getOrCreate()
full_table_name = f"glue_catalog.{target_db_name}.{target_table_name}"
# Read schema from one file (schema inference)
df = spark.read.parquet(s3_path)
schema = df.schema
# Create empty Iceberg table
empty_df = spark.createDataFrame([], schema)
if partitioned_cols:
    empty_df.writeTo(full_table_name).using("iceberg").partitionedBy(*partitioned_cols). .tableProperty("format-version", "2").create()
else:
    empty_df.writeTo(full_table_name).using("iceberg").tableProperty("format-version", "2").create()
logger.info(f"Created empty Iceberg table: {full_table_name}")
spark.sql(f"""
CALL glue_catalog.system.add_files(
  '{target_db_name}.{target_table_name}',
  'parquet.`{s3_path}`'
)
""")

When working with non-Hive partitioned datasets, a direct migration to Apache Iceberg using add_files might not behave as expected. See Appendix C for more information.

Considerations

Let’s explore two key considerations that you should address when implementing your migration strategy.

State management using DynamoDB control table

Use the following sample code snippet to update the state of DynamoDB table:

def update_dynamodb_record(self, s3_path, metadata_loc=None, error_msg=None):
    # Get current error message
    try:
        response = self.dynamodb.get_item(
            TableName='migration-control-table',
            Key={'s3_path': {'S': s3_path}}
        )
        current_error = response.get('Item', {}).get('error_message', {}).get('S', '')
    except:
        current_error = ""
    if error_msg:
        # Error case
        error_msg = (error_msg or "Unknown error")[:1000]
        update_expr = "SET error_message = :err"
        attr_values = {':err': {'S': error_msg}}
        if current_error:
            update_expr += ", prev_error_message = :prev"
            attr_values[':prev'] = {'S': current_error}
        update_kwargs = {'TableName': 'Iceberg_migration','Key': {'s3_path': {'S': s3_path}},'UpdateExpression': update_expr,'ExpressionAttributeValues': attr_values}
        self.logger.error(f"Set error for {s3_path}: {error_msg}")
    else:
        # Success case
        update_kwargs = {
            'TableName': 'Iceberg_migration',
            'Key': {'s3_path': {'S': s3_path}},
            'UpdateExpression': 'SET #s = :status, #m = :meta, #p = :prev, #e = :err',
            'ExpressionAttributeNames': {'#s': 'status','#p': 'prev_error_message','#e': 'error_message','#m': 'metadata_location'
            },
            'ExpressionAttributeValues': {
                ':status': {'S': 'Iceberg_Metadata_Populated and Registered'},
                ':prev': {'S': current_error},
                ':err': {'S': ''},
                ':meta': {'S': metadata_loc}
            }
        }
        self.logger.info(f"Updated DynamoDB status for {s3_path}: {metadata_loc}")

This ensures that any errors are logged and saved to DynamoDB as error_message. On successive retries, previous errors move to prev_error_message and new errors overwrite error_message. Successful operations clear error_message and archive the last error.

Protecting your data from unintended deletion

To protect your data from unintended deletion, never delete data or metadata files from Amazon S3 directly. Iceberg tables that are registered in AWS Glue or Athena are managed tables and should be deleted using the DROP TABLE command from Spark or Athena. The DROP TABLE command deletes both the table metadata and the underlying data files in S3. See Appendix D for more information.

Clean up

Complete the following steps to clean up your resources:

  1. Delete the DynamoDB control table
  2. Delete the database and tables
  3. Delete the EMR clusters and AWS Glue job used for testing

Conclusion

In this post, we showed you how to modernize your Parquet-based data lake into an Apache Iceberg–powered lakehouse without rewriting or duplicating data. You learned two complementary approaches for this in-place migration:

  • Migrate and register – Ideal for converting existing Hive-registered Parquet tables into Iceberg-managed tables.
  • add_files – Best suited for quickly onboarding raw Parquet data into Iceberg without rewriting files.

Both approaches benefit from DynamoDB centralized state tracking, which enables retries, error auditing, and lifecycle management across multiple datasets.

By combining Apache Iceberg with Amazon EMR, AWS Glue, and Amazon DynamoDB, you can create a production-ready migration pipeline that is observable, automated, and straightforward to extend to future data format upgrades. This pattern forms a solid foundation for building an Iceberg-based lakehouse on AWS, helping you achieve faster analytics, better data governance, and long-term flexibility for evolving workloads.

To get started, try implementing this solution using the sample tables (table1 and table2) that you created using Athena queries. we encourage you to share your migration experiences and questions in the comments.


Appendix A — Creating an EMR cluster for Hive metastore using console and AWS CLI

Console steps:

  1. Open AWS Management Console for Amazon EMR and choose Create cluster.
  2. Select Spark or Hive under applications.
  3. Under AWS Glue Data Catalog settings, make sure the following options are not selected:
    • Use for Hive table metadata
    • Use for Spark table metadata
  4. Configure SSH access (KeyName).
  5. Configure network (VPC, subnets, SGs) to allow access to S3.

AWS CLI steps:

aws emr create-cluster \
  --region us-east-1 \
  --name "IcebergHiveCluster711" \
  --release-label emr-7.11.0 \
  --applications Name=Hive Name=Spark Name=Hadoop \
  --ec2-attributes '{"KeyName":"<key-pair>","SubnetId":"<subnet-id>"}'  \
  --instance-groups '[
    {
      "Name":"Master",
      "InstanceGroupType":"MASTER",
      "InstanceType":"m5.xlarge",
      "InstanceCount":1
    },
    {
      "Name":"Workers",
      "InstanceGroupType":"CORE",
      "InstanceType":"m5.xlarge",
      "InstanceCount":2
    }
  ]' \
  --use-default-roles

Appendix B — EMR cluster with AWS Glue as Spark Metastore

Console steps:

  1. Open the Amazon EMR console, choose Create cluster and then select EMR Serverless or provisioned EMR.
  2. Under Software Configuration, verify that Spark is installed.
  3. Under AWS Glue Data Catalog settings, select Use Glue Data Catalog for Spark metadata.
  4. Configure SSH access (KeyName).
  5. Configure network settings (VPC, subnets, and security groups) to allow access to Amazon S3 and AWS Glue.

AWS CLI (provisioned Amazon EMR):

aws emr create-cluster \
  --region us-east-1 \
  --name "IcebergGlueCluster711" \
  --release-label emr-7.11.0 \
  --applications Name=Spark Name=Hadoop \
  --ec2-attributes '{"KeyName":"<key-pair>","SubnetId":"<subnet-id>"}' \
  --instance-groups '[
    {
      "Name":"Master",
      "InstanceGroupType":"MASTER",
      "InstanceType":"m5.xlarge",
      "InstanceCount":1
    },
    {
      "Name":"Workers",
      "InstanceGroupType":"CORE",
      "InstanceType":"m5.xlarge",
      "InstanceCount":2
    }
  ]' \
 --configurations '[{"Classification":"spark-hive-site","Properties":{"hive.metastore.client.factory.class":"com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory"}}]' \
 --use-default-roles

Appendix C — Non-Hive partitioned datasets and Iceberg add_files

This appendix explains why a direct in-place migration using an add_files-style procedure might not behave as expected for datasets that aren’t Hive-partitioned and shows recommended fixes and examples.

AWS Glue and Athena follow Hive-style partitioning, where partition column values are encoded in the S3 path rather than inside the data files. For example, following the Parquet dataset created in the Create Sample Parquet Dataset as a source section of this post:

s3://amzn-s3-demo-bucket/events/event_date=2024-09-01/hour=5/part-0000.parquet
s3://amzn-s3-demo-bucket/events/event_date=2024-09-02/hour=5/part-0001.parquet
  • Partition columns (event_date, hour) are represented in the folder structure.
  • Non-partition columns (for example, id, name, age) remain inside the Parquet files.
  • Iceberg add_files can correctly map partitions based on the folder path, even if partition columns are missing from the Parquet file itself.

Partition column

Stored in path

Stored in file

Athena or AWS Glue and Iceberg behavior

event_date Yes Yes Partitions inferred correctly
hour Yes No Partitions still inferred from path

Non-Hive partitioning layout (problem case)

s3://amzn-s3-demo-bucket/events/date/part-0000.parquet
s3://amzn-s3-demo-bucket/events/date/part-0001.parquet
  • No partition columns in the path.
  • File might not contain partition columns.

If you try to create an empty Iceberg table and directly load it using add_files on a non-hive layout, the following happens:

  1. Iceberg cannot automatically map partitions, add_files operations fail or register files with incorrect or missing partition metadata.
  2. Queries in Athena or AWS Glue will return unexpected NULLs or incomplete results.
  3. Successive incremental writes using add_files will fail.

Recommended approaches:

Create an AWS Glue table and use the Iceberg snapshot procedure:

  1. Create a table in AWS Glue pointing to your existing Parquet dataset.

You might need to manually provide the schema because glue crawler might fail to automatically infer it for you.

  1. Use Iceberg’ s snapshot procedure to convert and move the AWS Glue table into your target Iceberg table.

This works because Iceberg relies on AWS Glue for schema inference, so this approach ensures correct mapping of columns and partitions without rewriting the data. For more information, see Snapshot procedure.


Appendix D — Understanding table types: Managed compared to external

By default, all non-Iceberg tables created in AWS Glue or Athena are external tables, Athena doesn’t manage the underlying data. If you use CREATE TABLE without the EXTERNAL keyword for non-Iceberg tables, Athena issues an error.

However, when dealing with Iceberg tables, AWS Glue and Athena also manage the underlying data for the respective tables, so these tables are treated as internal tables.

Running DROP TABLE on Iceberg tables will delete the table and the underlying data.

The following table describes how the effect of DELETE and DROP TABLE actions on Iceberg tables in AWS Glue and Athena:

Operation What it does Effect on S3 data
DELETE FROM mydb.products_iceberg WHERE date = 2025-10-06; Creates new snapshot, hides deleted rows Data files stay until cleanup
DROP TABLE test_db.table1; Deletes table and all data Files are permanently removed

About the authors

Mihir Borkar

Mihir Borkar

Mihir is a seasoned AWS Data Architect with nearly a decade of experience designing and implementing enterprise-scale data solutions on AWS. He specializes in modernizing data architectures using AWS data analytical services, designing scalable data lakes and analytics platforms with a focus on efficient, cost-effective solutions. In his free time, Mihir loves to read about emerging cloud technologies and explore latest developments in AI/ML.

Amit Maindola

Amit Maindola

Amit is a Senior Data Architect with AWS ProServe team focused on data engineering, analytics, and AI/ML at Amazon Web Services. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.

Arghya Banerjee

Arghya Banerjee

Arghya is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers adopt and use the AWS Cloud. He is focused on big data, data lakes, streaming and batch analytics services, and generative AI technologies.

Fall 2025 SOC 1, 2, and 3 reports are now available with 185 services in scope

Post Syndicated from Tushar Jain original https://aws.amazon.com/blogs/security/fall-2025-soc-1-2-and-3-reports-are-now-available-with-185-services-in-scope/

Amazon Web Services (AWS) is pleased to announce that the Fall 2025 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 185 services over the 12-month period from October 1, 2024–September 30, 2025, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

Customers can download the Fall 2025 SOC 1 and 2 reports through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact. The SOC 3 report can be found on the AWS SOC Compliance Page.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs. As always, we value feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Tushar holds a Master of Business Administration from the Indian Institute of Management Shillong, India, and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CISM, CCSK, and CSXF certifications.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Nathan Samuel

Nathan Samuel
Nathan is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Nathan has a Bachelor of Commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

Gabby Iem

Gabby Iem
Gabby is a Program Manager at AWS. She supports multiple initiatives within AWS security assurance and has recently received her bachelor’s degree from Chapman University studying business administration.

Jeff Cheung

Jeff Cheung
Jeff is a Technical Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelor’s degrees in Information Systems and Economics from SUNY Stony Brook and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

Noah Miller

Noah Miller
Noah is a Compliance Program Manager at AWS and supports multiple security and privacy initiatives within AWS. Noah has 6 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

Will Black

Will Black
Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

Mozilla introduces Firefox Nightly RPM package repository

Post Syndicated from jzb original https://lwn.net/Articles/1055191/

Mozilla has announced
a repository with Firefox
Nightly channel
packages for RPM-based Linux distributions such as CentOS
Stream, Fedora, and openSUSE. Mozilla has provided a Debian repository
since 2023.

Note that this repository only includes the nightly builds of The
firefox-nightly package. Mozilla is not providing stable
builds as RPMs at this time. However, the package will not conflict
with a distribution’s regular firefox package; both packages
can be installed at the same time for those who wish to test the
nightly builds. See the blog post for instructions on setting up the
repository.

[$] An alternate path for immutable distributions

Post Syndicated from daroc original https://lwn.net/Articles/1054216/

LWN has had a number of articles on immutable distributions,
such as Bluefin and
Bazzite
, in recent years. These distributions have taken a variety of approaches, including
using

rpm-ostree
, filesystem snapshots, and
bootable container (bootc) images. But those
approaches, especially the latter, lead to extra complexity for a user
attempting to install new software, instead of just
using the existing package manager.

AshOS
(Any Snapshot Hierarchical OS) is an experimental AGPL-3-licensed
“meta-distribution” that tried a different approach more in line with
traditional package management. Although the project is no longer updated,
it remains usable, and can still shed some light on a potential alternate path for users
worried about adopting bootc-based approaches.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1055152/

Security updates have been issued by AlmaLinux (gpsd-minimal, jmc, kernel, kernel-rt, and net-snmp), Debian (apache-log4j2 and dcmtk), Fedora (exim, gpsd, mysql8.0, mysql8.4, python-biopython, and rust-lru), Mageia (firefox, nss and thunderbird), Oracle (container-tools:rhel8, gpsd-minimal, jmc, kernel, net-snmp, and uek-kernel), Red Hat (net-snmp), SUSE (chromium, go, harfbuzz-devel, kernel, libsoup, rust1.91, rust1.92, and thunderbird), and Ubuntu (apache2, avahi, and python-urllib3).

Could ChatGPT Convince You to Buy Something?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/01/could-chatgpt-convince-you-to-buy-something.html

Eighteen months ago, it was plausible that artificial intelligence might take a different path than social media. Back then, AI’s development hadn’t consolidated under a small number of big tech firms. Nor had it capitalized on consumer attention, surveilling users and delivering ads.

Unfortunately, the AI industry is now taking a page from the social media playbook and has set its sights on monetizing consumer attention. When OpenAI launched its ChatGPT Search feature in late 2024 and its browser, ChatGPT Atlas, in October 2025, it kicked off a race to capture online behavioral data to power advertising. It’s part of a yearslong turnabout by OpenAI, whose CEO Sam Altman once called the combination of ads and AI “unsettling” and now promises that ads can be deployed in AI apps while preserving trust. The rampant speculation among OpenAI users who believe they see paid placements in ChatGPT responses suggests they are not convinced.

In 2024, AI search company Perplexity started experimenting with ads in its offerings. A few months after that, Microsoft introduced ads to its Copilot AI. Google’s AI Mode for search now increasingly features ads, as does Amazon’s Rufus chatbot. OpenAI announced on Jan. 16, 2026, that it will soon begin testing ads in the unpaid version of ChatGPT.

As a security expert and data scientist, we see these examples as harbingers of a future where AI companies profit from manipulating their users’ behavior for the benefit of their advertisers and investors. It’s also a reminder that time to steer the direction of AI development away from private exploitation and toward public benefit is quickly running out.

The functionality of ChatGPT Search and its Atlas browser is not really new. Meta, commercial AI competitor Perplexity and even ChatGPT itself have had similar AI search features for years, and both Google and Microsoft beat OpenAI to the punch by integrating AI with their browsers. But OpenAI’s business positioning signals a shift.

We believe the ChatGPT Search and Atlas announcements are worrisome because there is really only one way to make money on search: the advertising model pioneered ruthlessly by Google.

Advertising model

Ruled a monopolist in U.S. federal court, Google has earned more than US$1.6 trillion in advertising revenue since 2001. You may think of Google as a web search company, or a streaming video company (YouTube), or an email company (Gmail), or a mobile phone company (Android, Pixel), or maybe even an AI company (Gemini). But those products are ancillary to Google’s bottom line. The advertising segment typically accounts for 80% to 90% of its total revenue. Everything else is there to collect users’ data and direct users’ attention to its advertising revenue stream.

After two decades in this monopoly position, Google’s search product is much more tuned to the company’s needs than those of its users. When Google Search first arrived decades ago, it was revelatory in its ability to instantly find useful information across the still-nascent web. In 2025, its search result pages are dominated by low-quality and often AI-generated content, spam sites that exist solely to drive traffic to Amazon sales—a tactic known as affiliate marketing—and paid ad placements, which at times are indistinguishable from organic results.

Plenty of advertisers and observers seem to think AI-powered advertising is the future of the ad business.

Highly persuasive

Paid advertising in AI search, and AI models generally, could look very different from traditional web search. It has the potential to influence your thinking, spending patterns and even personal beliefs in much more subtle ways. Because AI can engage in active dialogue, addressing your specific questions, concerns and ideas rather than just filtering static content, its potential for influence is much greater. It’s like the difference between reading a textbook and having a conversation with its author.

Imagine you’re conversing with your AI agent about an upcoming vacation. Did it recommend a particular airline or hotel chain because they really are best for you, or does the company get a kickback for every mention? If you ask about a political issue, does the model bias its answer based on which political party has paid the company a fee, or based on the bias of the model’s corporate owners?

There is mounting evidence that AI models are at least as effective as people at persuading users to do things. A December 2023 meta-analysis of 121 randomized trials reported that AI models are as good as humans at shifting people’s perceptions, attitudes and behaviors. A more recent meta-analysis of eight studies similarly concluded there was “no significant overall difference in persuasive performance between (large language models) and humans.”

This influence may go well beyond shaping what products you buy or who you vote for. As with the field of search engine optimization, the incentive for humans to perform for AI models might shape the way people write and communicate with each other. How we express ourselves online is likely to be increasingly directed to win the attention of AIs and earn placement in the responses they return to users.

A different way forward

Much of this is discouraging, but there is much that can be done to change it.

First, it’s important to recognize that today’s AI is fundamentally untrustworthy, for the same reasons that search engines and social media platforms are.

The problem is not the technology itself; fast ways to find information and communicate with friends and family can be wonderful capabilities. The problem is the priorities of the corporations who own these platforms and for whose benefit they are operated. Recognize that you don’t have control over what data is fed to the AI, who it is shared with and how it is used. It’s important to keep that in mind when you connect devices and services to AI platforms, ask them questions, or consider buying or doing the things they suggest.

There is also a lot that people can demand of governments to restrain harmful corporate uses of AI. In the U.S., Congress could enshrine consumers’ rights to control their own personal data, as the EU already has. It could also create a data protection enforcement agency, as essentially every other developed nation has.

Governments worldwide could invest in Public AI—models built by public agencies offered universally for public benefit and transparently under public oversight. They could also restrict how corporations can collude to exploit people using AI, for example by barring advertisements for dangerous products such as cigarettes and requiring disclosure of paid endorsements.

Every technology company seeks to differentiate itself from competitors, particularly in an era when yesterday’s groundbreaking AI quickly becomes a commodity that will run on any kid’s phone. One differentiator is in building a trustworthy service. It remains to be seen whether companies such as OpenAI and Anthropic can sustain profitable businesses on the back of subscription AI services like the premium editions of ChatGPT, Plus and Pro, and Claude Pro. If they are going to continue convincing consumers and businesses to pay for these premium services, they will need to build trust.

That will require making real commitments to consumers on transparency, privacy, reliability and security that are followed through consistently and verifiably.

And while no one knows what the future business models for AI will be, we can be certain that consumers do not want to be exploited by AI, secretly or otherwise.

This essay was written with Nathan E. Sanders, and originally appeared in The Conversation.

How to put data first in K–12 AI education by using data case studies

Post Syndicated from Manni Cheung original https://www.raspberrypi.org/blog/how-to-put-data-first-in-k-12-ai-education-by-using-data-case-studies/

In Germany, as in many countries, AI topics are rapidly entering formal computer science education. Yet, this haste often risks us focusing on fleeting technological developments rather than fundamental concepts. As computer science educator Viktoriya Olari, from Free University of Berlin, discovered in her research, the fundamental role of data, which powers most modern AI systems, is critically underestimated in many existing frameworks. If students are to become responsible designers of such systems, they can’t afford to treat AI as an opaque box. Rather, they must first master the messy, human process that begins with the data itself.

Viktoriya Olari, from Free University of Berlin.
Viktoriya Olari

In our October research seminar, Viktoriya shared the results of her work over the last four years on how schools can shift the focus from the latest technologies to the underlying data. Her research offers a clear structure for what young people should learn about data and how teachers can make it work inside ordinary classrooms.

Why begin with data?

Viktoriya’s analysis of existing AI education frameworks found the data domain is underrepresented, with essentials such as data cleaning often not addressed at all. She argues that, because modern AI systems are data driven, students need both language and routines for working with data: being able to name concepts like training vs test data, data quality, and bias, and to explain practices such as collection, cleaning, and pre-processing. That’s the rationale for teaching data concepts and practices first, and then placing modelling inside an explicit, staged lifecycle.

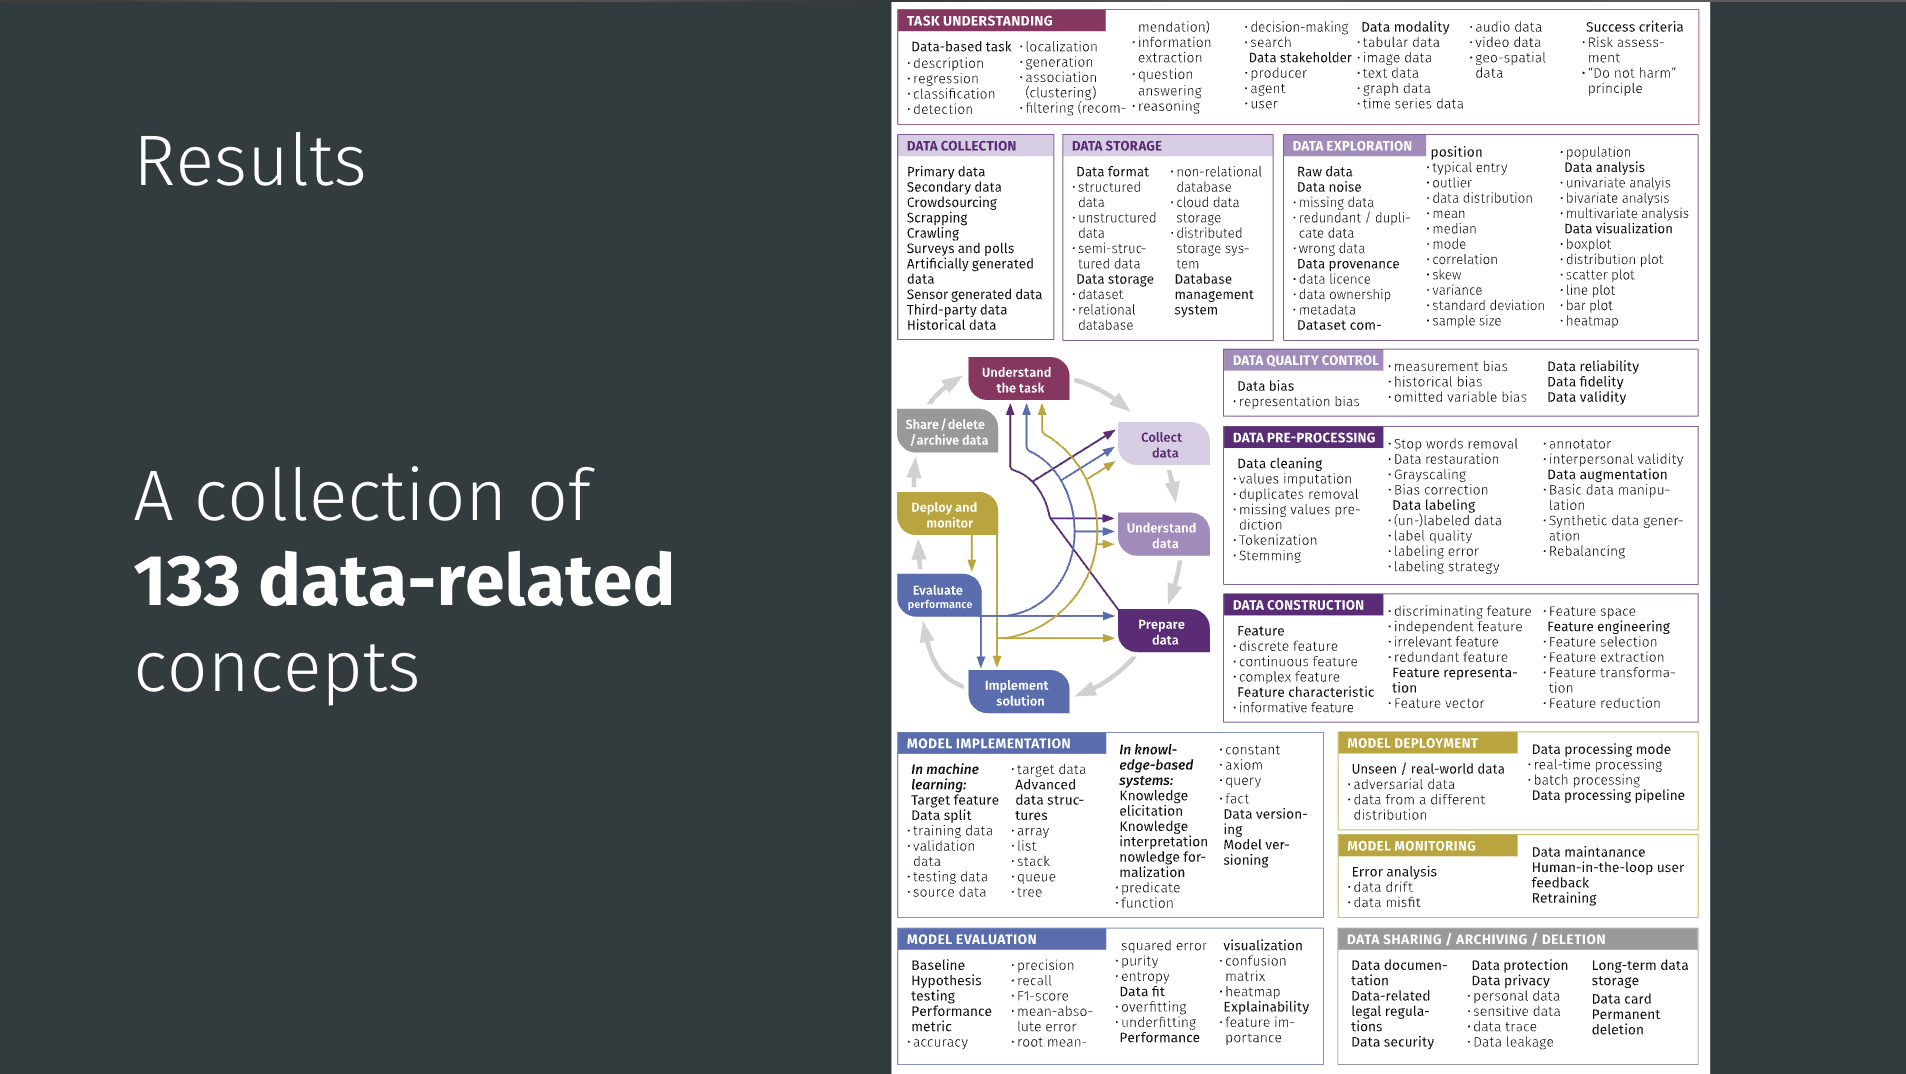
Word clouds for two foundational components: data concepts and data practices.
A slide from Viktoriya’s presentation. Click to enlarge.

Her talk presented this argument in the German school context, where AI topics are entering state curricula quickly. Her critique targets how existing frameworks fail to address data and how that gap undermines responsible evaluation and design. The proposed model centres data by pairing an eight-stage, data-driven lifecycle with a curated set of key concepts and practices, and by making “data-based judgment skills” a key outcome.

Viktoriya’s work organises this understanding into two foundational components: data concepts (the vocabulary, e.g. training/test data, data quality, overfitting) and data practices (the actions, e.g. collect, clean, train, evaluate).

A lifecycle for learning

Viktoriya’s framework is built around an eight-stage data lifecycle, stretching from defining a task through gathering, preparing, modeling, evaluating, and finally sharing or archiving results. Inside that backbone she has identified two layers of learning targets:

  • Data concepts – roughly a hundred ideas that give teachers and students a common language, from “training vs. test data” and “bias” to “features”, “labels”, and “provenance”.
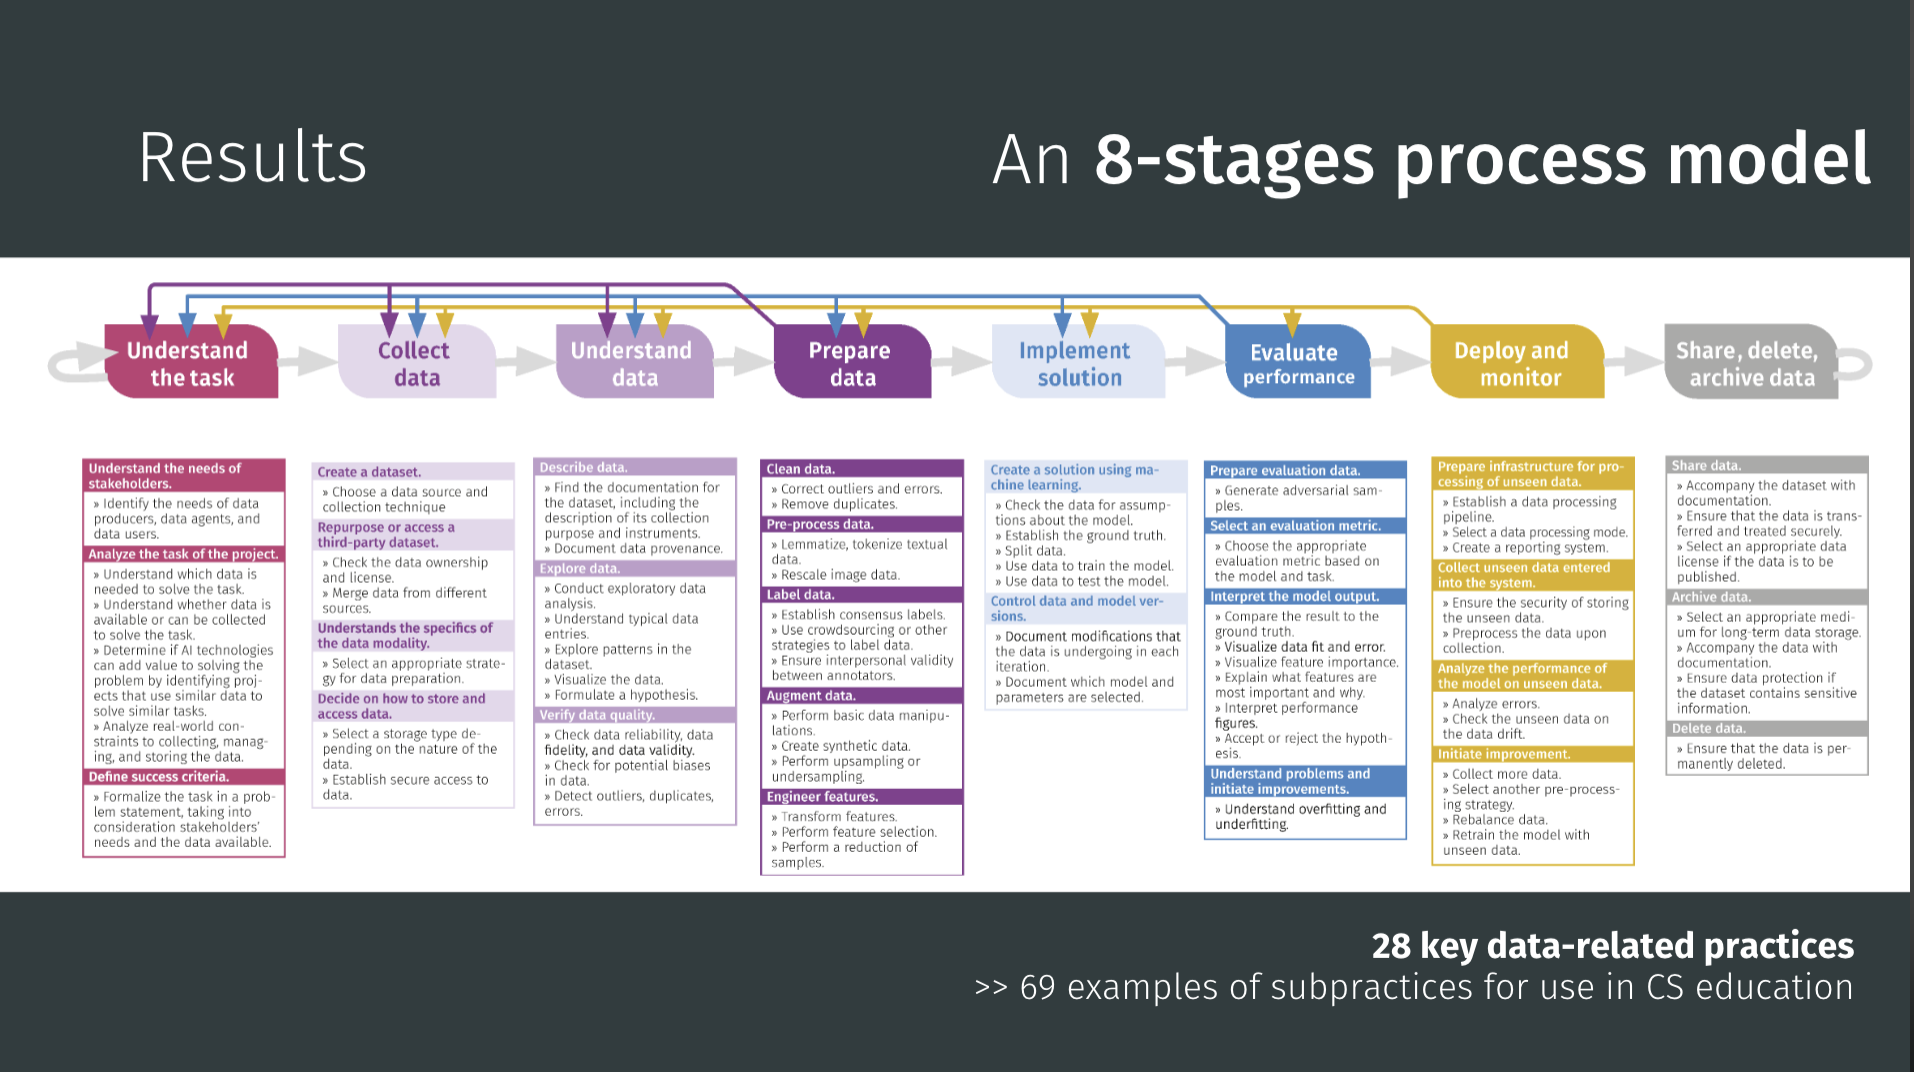
  • Data practices – 28 kinds of hands-on work (and 69 subpractices) that materialise those ideas: for instance collecting, cleaning, splitting datasets, checking quality, training and evaluating models, and handling privacy and deletion responsibly.

More details are available in her work on data-related concepts and practice.

Viktoriya’s 8-stage process model of the data-driven lifecycle.
A slide from Viktoriya’s presentation. Click to enlarge.

Viktoriya’s 8-stage process model of the data-driven lifecycle. It serves as a guide for curriculum developers and teachers, outlining 28 key data-related practices and providing 69 examples of subpractices for use in K–12 computer science education.

A collection of 133 key data-related concepts.
A slide from Viktoriya’s presentation. Click to enlarge.

A collection of 133 key data-related concepts. These concepts are organised according to the eight stages of the data-driven lifecycle and provide the foundational vocabulary for teaching AI education.

Making it teachable

Viktoriya’s team set out to redesign the format so that real data work could happen within ordinary lessons. They ended up with three “Data Case Study” architectures, each using authentic datasets and domain questions. The materials are supported by Orange 3, an unplugged machine learning and data visualisations tool familiar to the teachers participating. Variants emerged across three design cycles to address specific challenges, but teachers choose among them based on learning objectives and class context.

  1. Bottom-up: Students create a workflow step by step (e.g. import, inspect, clean, transform, split, train, evaluate). This approach is excellent for procedural fluency, but teachers reported an over-emphasis on operating Orange and too little reflection on the lifecycle unless explicit reflection is added. 
  2. Top-down: Students start from a prepared workflow, read plots, infer the role of each branch, identify issues in the data/practices, and justify changes. This architecture directly counters the reflection gap seen in bottom-up and leans into reasoning rather than routine. 
  3. Puzzle-like: Using “widgets,” visualisations of data tables, that stand for parts of a data pipeline, students rebuild a valid flow collaboratively. This encourages discussion, works without devices, and makes thinking visible.
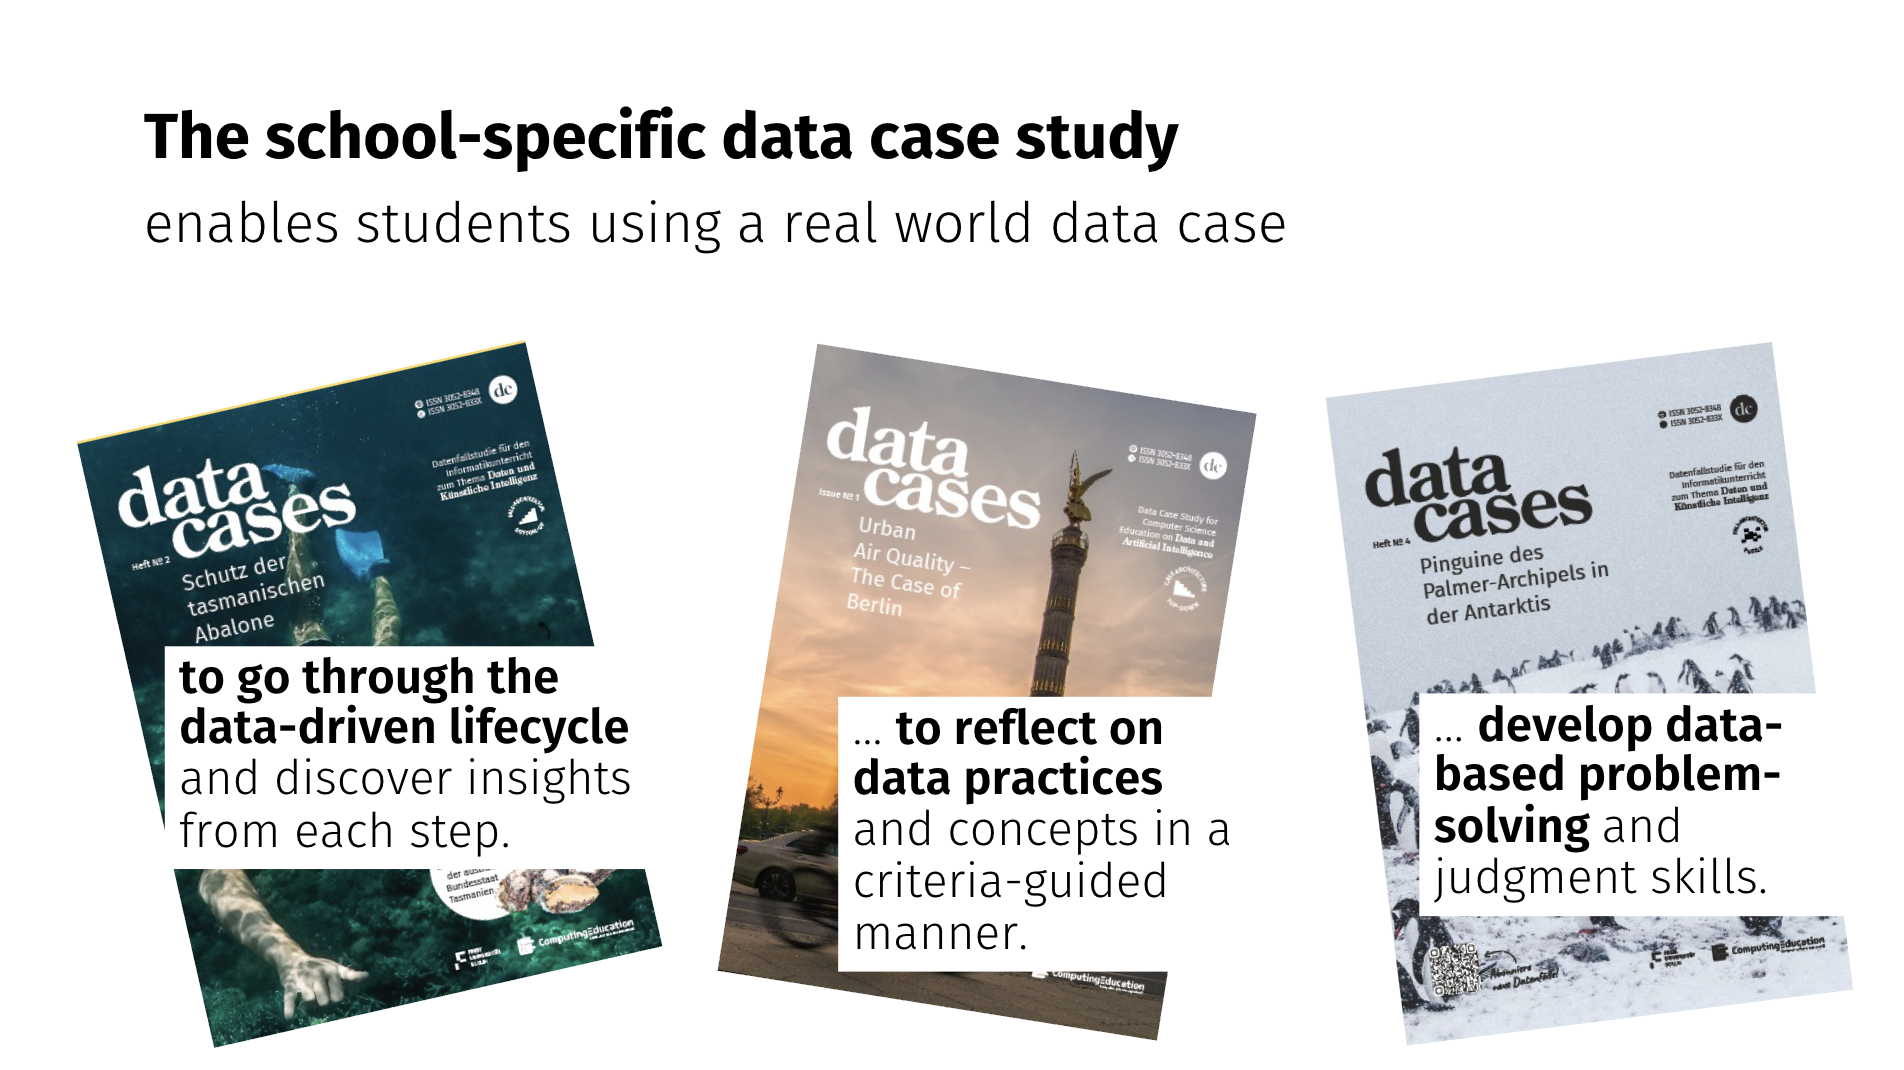
The school-specific data case study
A slide from Viktoriya’s presentation.

The data case study method uses real-world data and context to help students achieve three key learning outcomes: go through the data-driven lifecycle, reflect on data practices and concepts in a criteria-guided manner, and develop data-based problem-solving and judgment skills.

What happened in the German classrooms

Viktoriya’s team ran three design cycles with small groups in Germany, with students aged 14 to 15. Each cycle lasted around 48 hours of teaching. Because participating teachers already knew Orange 3, the emphasis was on pedagogy rather than software training.

The projects drew on manageable real-world data: spreadsheets, time-series sets, a few geographical samples. Two examples are:

  • Forecasting Berlin air quality – Students explored how data quality, feature choice, and evaluation metrics shape predictions, then argued which model best answered the civic question.
  • Classifying Tasmanian abalone – A deceptively simple dataset that invites talk about imbalance, feature engineering, and what counts as “good enough” accuracy.

Some groups experimented with collecting their own sensor data, a plan that occasionally failed when the hardware didn’t cooperate. However, even that became part of the lesson: reliability, risk, and missing data are real features of data science, not mistakes to hide.

A computing classroom filled with learners

Student work reflected the three architectures. In the bottom-up groups, guided builds produced complete workflows and concise reflections, while top-down groups submitted annotated screenshots and critiques, and the puzzle-based lessons ended with posters and verbal presentations. Across them all, assessment focused on reasoning: not whether the “right” model appeared, but whether students could explain the stage they were in and justify their choices.

Teaching resources

Everything Viktoriya described is open and classroom-ready (currently in German). The computingeducation.de/proj-datacases hub hosts teacher guides, student tasks, and sample Orange 3 files. The growing library of data cases covers topics from climate data to air quality analytics.

Why it matters now

In the UK, a curriculum review has been recently released and along with the Government’s response. Across Europe and beyond, education systems are racing to add AI content to their curricula. Tools will come and go, and benchmarks will keep moving. What endures is the capacity to reason about data: to know what stage of work you’re in, what evidence supports your decisions, and what trade-offs you’re making. That is why Viktoriya’s contribution is unique — it gives teachers a map, a shared vocabulary, and practical ways to make data visible and the focus of discussion in schools.

You can read this blog to see how we’ve used Viktoriya’s framework in our work designing a data science curriculum for schools.

Join our next seminar

Join us at our seminar on Tuesday 27 January from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about how to teach about neural networks in Junior High Schools in Ghana.

To sign up and take part, click the button below. We’ll then send you information about joining.

We hope to see you there. This will be the final seminar in our series on teaching about AI and data science — the next series focuses on how to teach about applied AI across subjects and disciplines.

You can view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.


Teachers in England, take part in our new data science study

We’re looking for upper key stage 2 teachers in England who want to join our new collaborative study exploring how to teach learners aged 9 to 11 about data-driven computing. The study will look at:

  • How Computing teachers currently approach topics related to data-driven computing
  • What key ideas pupils need to understand
  • How pupils make sense of data and probability

Our aim for the study is to find practical ways for Computing teachers to build young people’s confidence in working with data in lessons. The study will involve two workshops held throughout 2026.

Register your interest by filling in this form.

The post How to put data first in K–12 AI education by using data case studies appeared first on Raspberry Pi Foundation.

Манипулацията – този стар и все тъй полезен занаят

Post Syndicated from Полковник А. original https://www.toest.bg/manipulatsiyata-tozi-star-i-vse-tuy-polezen-zanayat/

Манипулацията – този стар и все тъй полезен занаят

Седя пред камината във вилата си и чета поредната глупост за Държавна сигурност (ДС). Някога тази организация, към която принадлежах, беше страшна и името ѝ се споменаваше шепнешком. Днес куцо и сакато се избива да плещи за ДС, защото имаме свобода на словото. Която при това носи доходи, често нелоши, и то невинаги правопропорционални на качеството на произведението. И понеже горкото слово няма с какво да се отбранява, налага се хора като мен от време на време да му помагат.

Някога четяхме между редовете, днес хората дори и редовете не четат. А на старите професионалисти като мен им остава да наблюдават с досада аматьорските опити за манипулация. Освен, разбира се, ако не са още в играта. Защото

илюзията, че ДС е изчезнала, е точно това – илюзия. Докато има хора като нас, има я и нея.

В миналото службите – не само ДС, но и други – често манипулираха общественото мнение и обществените процеси в тогавашната Народна република България. Сега също има много манипулации. И трябва да ви кажа, че в България са активни множество тайни служби – не само онези, за които по принцип подозираме, а и редица други, за които дори не се досещаме. Или поне не веднага.

Обикновено се говори за ролята на руските тайни служби, която е очевидна за всеки познаващ техния стил на работа и историята на ангажимента им към страната ни. Руснаците залагат на сигурното, пък и донякъде им липсва въображение, затова сценариите им се разпознават по целия свят. Споменават се и американските служби, макар че, честно казано, не бих ги окачествил като особено успешни – поне не в настоящия момент – нито в България, нито в региона. Времената се промениха и явно с нас вече не се занимават най-добрите в професията. Чудя се дали да се радвам, или да се плаша.

Странното е, че често се изпускат от внимание други служби –

включително от държави в ЕС и в Западна Европа, както и от балкански страни, които работят доста активно в България. Такива без съмнение са турските тайни служби – особено когато наближават избори. Същото може да се каже и за някои от службите на Западните Балкани, наследниците на легендарната югославска УДБА [Управа државне безбедности (Управление за държавна сигурност) – б.р.] – например службите на Сърбия и на Северна Македония, за които бих казал, че са изключително успешни.

Ето пример – успешната манипулация както в Македония, така и в България по въпроса за присъединяването на Македония към ЕС. Службите там успяха да наложат наратива, че България пречи на започването на преговорите за членство. Абсолютно невярно. Истината е, че македонското правителство подписа документ с ЕС, в който са изложени условията за започване на тези преговори. Обръщам ви внимание – документът вече е подписан. Самото му съществуване обаче се премълчава или не се споменава достатъчно ясно, а текстът му в Македония е почти недостъпен.

По същия начин в българското общество тези служби умело използват наративи, които събуждат страсти и предизвикват емоционални, често остри реакции – типична форма на взаимна манипулация. Това създава среда, в която цивилизованият дискурс и конструктивните решения стават невъзможни. Същевременно те успяват да наложат македонския наратив в устата на редица западноевропейски политици и журналисти. Това е изключително успешна кампания по дезинформация – и колкото и парадоксално да звучи, от професионална гледна точка заслужава уважение.

Ето защо, на първо място, трябва да се научим да разпознаваме кога ни манипулират.

Един от най-сигурните индикатори е да си дадем сметка дали една кампания апелира към разума ни, или към чувствата ни. Когато се цели емоционална реакция, а не рационална преценка, почти сигурно става дума за манипулация. Важно е да не реагираме първосигнално, а да обмислим внимателно поведението си. Това само по себе си често прави манипулативния процес неефективен.

В годините на социализма не само българската ДС манипулираше обществото – това се правеше от тайните служби на всички комунистически режими. В голяма степен именно затова бяха създадени – да контролират процесите както по отношение на външни заплахи, така и на вътрешни.

С времето, когато недоволството от лошите икономически резултати и ниския стандарт на живот започна да нараства, манипулациите се засилиха. Целта беше да се укрепи и задържи властта на комунистическите партии възможно най-дълго, като вината за неуспехите се прехвърля върху някой друг. Това нямаше как да стане без манипулация – и в службите изиграхме голяма роля в този процес.

Искам да напомня на по-младите читатели, че тогава нямаше интернет, а върху средствата за масова информация се налагаше сериозна цензура. Но имаше и други, не по-малко ефективни начини да се манипулира общественото мнение. Няма сега да говоря подробно за агентурната мрежа, но ще спомена т.нар. агенти на влияние.

Това бяха хора с обществен авторитет – интелектуалци, преподаватели, известни личности, а дори и на местно ниво – популярни хора, които можеха да бъдат използвани за разпространяване на слухове и за налагане на определено обществено мнение. Лица, които имаха достъп до интимния живот на хората – лекари, лечители, духовници, – също биваха използвани за такива цели. Слуховете в България винаги са били изключително ефективно средство за манипулация. И днес продължават да се използват успешно – не само от службите.

Ще дам пример с т.нар. Възродителен процес.

Всичко започна с напълно необосновани слухове, че хората от малцинствата в България, видите ли, сами искали да бъдат преименувани. Това, разбира се, не беше истина, но целеше да легитимира процеса в очите на обществото и особено на образованите хора и интелектуалците. След това се използваха слухове за противопоставяне, направи се административна реформа за разпокъсване на общностите и накрая се стигна до обвинения в тероризъм. Процесът завърши с етническо прочистване и глупавото изгонване на наши съграждани извън страната. Толкова необосновано, че предизвика негативна реакция дори от Москва и допринесе за смяната на Живков през 1989 г.

Този пример показва колко опасна може да бъде манипулацията, когато излезе извън контрол. Тогава се постига обратен ефект – и в крайна сметка тя излиза твърде скъпо за онези, които я използват. Най-лошото е, че в тези процеси винаги има невидими жертви – хора, които страдат, без да са замесени.

Чувал съм, че днес обществото се манипулира по-лесно, защото има интернет, смартфони и достъп до всеки човек. Всъщност не е съвсем така.

За мен първият фактор, който улеснява манипулацията, е липсата на критично мислене и на функционална грамотност. Както споменах в началото, по времето на комунизма бяхме научени да четем между редовете и да не вярваме на официозите на партията, които разпространяваха основно пропаганда. Това налагаше и формата, под която манипулацията се поднасяше.

Ще спомена още едно „активно мероприятие“ – първата апокрифна книга за Ванга. Тя беше напечатана на пишеща машина, разпространяваше се от ръка на ръка, копирана на индиго или циклостил. Мнозина я мислеха едва ли не за откровение, а всъщност всяка буква в книгата беше дело на ДС.

Но ние бяхме аматьори, особено в сравнение с колегите от КГБ или дори от ЩАЗИ.

Не на последно място заради факта, че последните говореха същия език като в Западна Германия.

Мога да дам много примери, но ще се огранича до няколко общи наблюдения. Създаваха се документални филми, телевизионни предавания, пишеха се книги и дори научни статии с изключително висок – ако мога така да се изразя – манипулативен „професионализъм“. Интересното беше, че в Източна Германия съществуваше и откровена манипулация – пропагандни телевизионни предавания, които много лесно се разпознаваха като такива. Типичен пример беше „Черният канал“ на Фон Шницлер – източногерманския еквивалент на днешния руски пропагандист Соловьов. Арогантен, неприятен и банален.

Повечето източногерманци, включително и масовата аудитория, възприемаха тези предавания като евтина пропаганда и не им обръщаха особено внимание. Това, което обаче не можеха да забележат, беше, че тази груба пропаганда всъщност прикриваше истинската манипулация – много по-фина и далеч по-ефективна. Тя се подготвяше от цяла експертна група начело с журналистка, която имаше научна степен. Доколкото зная, тази дама все още е жива и здрава, затова ще я спомена само като д-р К. Материалите, подготвяни от нейния екип, бяха с толкова високо качество, че често се препечатваха и тиражираха в западни медии, които не разпознаваха манипулацията.

Сега е много интересно да се наблюдава как се разпространяват изключително абсурдни, тотално неверни и лесно оборими твърдения и слухове. Ако човек познава техниките и технологиите на различните тайни служби, може да проследи кой всъщност ги е „родил“.

Най-лесният пример е темата за еврото, към което преминахме през януари.

Преди самия процес на въвеждане имаше силно поляризирана обществена дискусия, в която и двата полюса разпространяваха непълна и силно изкривена информация.

От едната страна бяха „защитниците на българския лев“, които рисуваха апокалиптични сценарии при евентуален преход към еврото. От другата страна стояха привържениците на въвеждането му, които представяха процеса като почти чисто техническа подробност – изтъкваха, че България от години живее в условията на валутен борд и че преминаването към еврото може да има единствено благоприятни последици за страната.

Моето мнение е, че нещата не са толкова еднозначни – преминаването към еврото има положителни страни, но съдържа и рискове. За съжаление, трезва и балансирана дискусия по този въпрос на практика липсваше. Докладът на Европейската централна банка, която оцени готовността на България, беше представен в повечето медии едностранчиво и бих казал, доста повърхностно – като изцяло „положителен“.

Всъщност, ако човек прочете самия доклад – а аз си направих този труд, – ще види, че той не е еднозначно положителен. Макар да посочва, че формално България е готова за членство в еврозоната и е изпълнила критериите, в него се повдигат и редица сериозни въпроси, свързани с устойчивостта на финансовата ни система и с нейната изключителна уязвимост на външни рискове.

Тези предупреждения често са представени чрез графики, а не чрез директен текст. За съжаление, почти никой не си направи труда да направи задълбочен анализ именно на официалния документ, въз основа на който се оценява готовността ни.

Но едно е сигурно – след приемането на еврото нашата финансова дисциплина и готовността ни да реагираме на рискове в никакъв случай не бива да отслабват. Опасението ми обаче е, че може да се случи точно това.

Като добър пример за манипулация могат да се разгледат и протестите срещу коалиционното правителство на Желязков,

при които десетки хиляди души излязоха на улицата. От една страна, имаше напълно легитимно недоволство срещу безобразния начин, по който правителството предложи и се опита да приеме бюджета – без обществено обсъждане. Честно казано, наблюдавайки този процес, си спомнях нескопосаните практики на тоталитарната държава, когато подобни решения се налагаха „отгоре“, без диалог. И неизменно се проваляха.

От друга страна обаче, се появиха политически фигури, които решиха да „възседнат“ протеста – нещо, което в България сме виждали многократно – с цел да извлекат политически дивиденти. Започна опростяване на ситуацията, наложиха се лозунги и формулировки, които не подлежат на ясна интерпретация и въздействат не върху разума, а върху емоциите на хората. Появиха се устойчиви изрази и емоционални спусъци, като „касички“, „прасета“ и други подобни – типичен пример за емоционално натоварен език, който измества смисъла.

От гледна точка на манипулацията това беше успех. От гледна точка на резултатите – не беше постигнато нищо съществено.

Това коалиционно правителство, прочее, беше съставено по такъв безобразен начин, че от него трудно можеше да се очаква каквото и да било. Важно е обаче да се отбележи, че дори в този като цяло лош бюджет бяха заложени разходи за отбрана и за укрепване на силовите структури – нещо, което в момента е стратегически приоритет не само за България, но и за цяла Европа.

Не е тайна, че Европа се въоръжава.

Твърде дълго разчитахме „добрият ловец“ да ни спаси. „Добрият ловец“ обаче недвусмислено ни показа, че има други планове. И делото за спасяването на давещите се отново се превърна в дело на самите давещи се, ако ми позволите тази заемка от Илф и Петров.

В момента Европа се опитва да изгради собствена отбранителна система. Очакват се засилени опити за дестабилизация на отделни държави – включително и чрез актове на агресия. Затова е изключително важно нашите силови структури да бъдат на адекватно ниво.

Поради тази причина вторият ешелон – професионалистите във властта – бяха заложили високи разходи за отбрана и за силовите структури. Това са бюджети, които винаги са апетитни за онези политически актьори, които се интересуват от корупция. Там, където има големи военни бюджети, се краде – често много.

Но там, където няма никакви разходи за отбрана и за силови структури, както се очертава картината в момента, рискът може да бъде още по-голям.

Затова с бламирането на бюджета – колкото и калпав да беше той – опозицията може би по-скоро избоде очи, отколкото изписа вежди.

Аз оставам умерен оптимист и смятам, че ако хората се вслушват повече в съветите на професионалистите и вземат по-малко прибързани решения, продиктувани от тесни политически интереси, има шанс да се постигне нещо градивно. Дано не греша.

Но на следващите избори, разбира се, очаквам изключително много манипулации. Те вече започнаха.

От едната страна се чертаят апокалиптични картини – месеци, дори години на дестабилизация, мизерия и разпад. От другата страна се използват устойчиви словосъчетания и лозунги, които атакуват нервната система на хората, а не мисловните им процеси.

Тоест нищо ново под слънцето.

Ако ми позволите това обобщение, най-голямото зло е неинформираният гласоподавател.

Моят съвет е прост: когато някой ви представя дадена информация, винаги търсете първоизточника ѝ и си задавайте въпроса „Защо?“ – не веднъж, а пет пъти или поне три. Това не е моя идея. Принципът произхожда от японската школа по управление на качеството и се свързва най-често със Сакичи Тойода – създател на метода „Петте защо“, който по-късно е широко използван и в анализа на публични политики. Според мен и три „Защо?“ много често са напълно достатъчни, за да ви отведат до първопричината и да покажат дали не става дума за манипулация.

А като първоначален тест винаги си задавайте още един въпрос: въздейства ли материалът, който четете, слушате или гледате, върху мисълта ви – или върху емоциите ви? Ако отговорът е второто, в 99% от случаите става дума за манипулация.

Проверявайте. И не се хващайте.

Желая ви успех.


Не знаем дали някой пише на полковника (по Маркес), но Полковник А. със сигурност пише на нас. Той държи на своята анонимност и по изключение ще я приемем. Защото в случая разказът е по-важен от автора. Особено когато става дума за миналото, което отказва да си тръгне. Четете с едно (или с няколко) наум.

Партийните системи по света и де е България в тях

Post Syndicated from original https://www.toest.bg/partiynite-sistemi-po-sveta-i-de-e-bugariya-v-tyah/

Партийните системи по света и де е България в тях

Когато Асен Василев постави като цел пред ПП–ДБ спечелването на над 50% от гласовете на следващите предсрочни избори, водещият на „Панорама“ Бойко Василев възкликна, че това не е реалистично. Председателят на ПП обаче заяви, че е абсолютно възможно, тъй като мащабът на протестите срещу кабинета на Росен Желязков е сравним с този срещу правителството на Жан Виденов от 1997 г. Социологическите изследвания обаче сочат, че по-близка до действителността е перспективата на водещия на „Панорама“. Мнозина се питат защо е така и каква е причината у нас винаги да имаме това, което във Великобритания наричат hung parliament [висящ, увиснал парламент – б.р.] – състав на Народното събрание, при което нито една партия няма абсолютно мнозинство.

По принцип в България всички разбираме от две неща – политика и футбол. Може би затова и двете са на това дередже. В действителност обаче липсата на достатъчно адекватно гражданско образование е една от причините хората да се подвеждат в очакванията си от изборите и от това, което се случва след тях. 

Напоследък разочарованието стана толкова силно, че избирателите масово се оттеглиха от участие, което свидетелства за криза на представителността. 

Преведено на прост език, това означава, че зад партиите в парламента не стоят достатъчно хора, че народът да чувства властта „като своя“. Но дори когато участието е по-масово, резултатите рядко са удовлетворителни за партийните лидери, а в резултат техните най-запалени поддръжници обявяват избирателите за „тъпи“. Народът прост, животът – тежък, скучен, както е казал поетът.

Всъщност не само средностатическият избирател, а дори силно ангажираният политически гражданин най-често не разбира достатъчно от политика. Това се получава, защото съществува прост набор от знания, които не са му преподадени в училище, а много политолози напускаме сферата на специалността си, за да влезем в ролята на политически агитатори. Така анализите ни опитват да привлекат четящите или гледащите ги за каузата на дадена партия, вместо да им помогнат да разбират по-добре политическите процеси. Навремето в лекциите, на които имах честта да присъствам, проф. Петър-Емил Митев изрично направи разлика между политолога и политическия агитатор. Без да отрича правото на съществуване на втория, просто за да подчертае, че ролята му е различна. 

Затова и понякога се шегувам, че ми се иска у нас да има хора, които говорят за политика така спокойно и обективно, както инженер Иван Тенчев за Формула 1. Но ако чакам да се появи такъв човек, може и целият ми живот да мине, затова ще опитам да се заема с тази роля. Доколкото ми позволяват възможностите, разбира се. Аз също съм човек със своите пристрастия, нямам самочувствието на чак такъв експерт, а освен това говоря по-горе за дефицитите в образованието от личен опит – чак при започване на следването си разбрах, че информацията, която съм натрупал от четене на журналистически материали, все още не се е превърнала в знания.

Желанието ми е да обясня защо целта, поставена от Асен Василев пред ПП–ДБ, е трудно постижима, а ситуацията не е сравнима с тази от 1997 г. Жокер – не е (само) защото протестите от декември не бяха гладен бунт както тези срещу Виденов. За целта ще се опра на професор Бари Аксфорд и съавторите му, които в учебника Politics: An Introduction (изданието от 2002 г.) запознават студентите с чудния свят на политологията, в който бързо разбираш, че нищо не си разбирал (което според Сократ е пътят към мъдростта), а потреблението на огромен брой публицистика само е вкарало мозъка ти в абсолютна мъгла. Най-малкото защото между научна и публицистична статия разликата е голяма и те дори се класифицират по различен начин, когато цитираме извори в дисертация например – наръчникът на проф. Мавродиева и проф. Тишева е отличен източник, от който незапознатите могат да се информират за разликата.

По света в демократични условия се срещат няколко вида партийни системи, 

споменати и в цитирания по-горе учебник. Нека прелетим над тях, за да опитаме да преценим къде в тази координатна система се намираме. Няма да се спирам на миналото ни, когато България е била тоталитарна държава, въпреки „доблестните“ усилия на някои политически сили да се върнем в това положение.

В света се срещат демократични партийни системи, които въпреки това са с една доминираща политическа партия. Изборите са свободни, честни и под надзора на международни наблюдатели. Ала поради определени причини една партия има постоянно надмощие. Днес типичен пример за това е Япония, където управляват консервативните либералдемократи от партия „Джиминто“ (в „Тоест“ вече съм обяснявал защо консервативен либералдемократ не е оксиморон). Дълго време и Индия беше пример за такава страна. Партията на Националния конгрес, свързвана с клана Ганди–Неру, печелеше „битка след битка“ (по Пол Томас Андерсън) на избори, защото беше свързвана с националноосвободителното движение в страната. Напоследък тази практика се промени заради успехите на консерваторите от партията на премиера Нарендра Моди. Това е нормален за една демокрация развой на събитията, тъй като националното освобождение вече се отдалечава във времето. В ЮАР то е по-прясно и затова Конгресът на Мандела все още държи властта, въпреки обвиненията в корупция.

Ние обаче определено не принадлежим към тази система. Българските граждани не гласуваха масово за опозиционния СДС, когато комунистическият режим падна, а дори и след Освобождението от османско владичество се наблюдава разделение на либерали и консерватори.

Следващият тип системи, заради които според мен идват заблудите у нас, са двупартийните демократични системи. Изборите са свободни и честни, но се доминират от две партии. Най-яркият пример за това са САЩ. В някогашната си статия „Трети в игра за двама“ описах донкихотовците, опитващи се да пробият доминацията на демократите и републиканците, но истината е, че каузата им е безнадеждна. Не толкова изразени, но като цяло също двупартийни са системите на Великобритания (консерватори, лейбъристи) и Австралия (десни либерали, лейбъристи).

В първите години от Прехода, когато на избори доминираха СДС и БСП, изглеждаше, че България се насочва към този модел, с важното уточнение, че имаше силен трети играч в лицето на ДПС, който влизаше в ролята на балансьор. Именно състоянието на партийната ни система от този период допринесе за убедителните победи на ОДС от 1997 г., а преди това, през 1994 г. – на БСП. Появата на НДСВ през 2001 г. обаче разби тази система, което бе последвано от още пробиви.

Причината да не останем двупартийна система вероятно е в това, че представителството в Народното събрание е пропорционално. 

Обикновено мажоритарните системи водят до оформянето на две доминиращи партии и е добре да го имаме предвид на фона на периодично подновяващите се дебати за преминаване към мажоритарно избран парламент. Това се получава, защото при тези системи изборите за всеки от народните представители са отделни и само водещите партии имат възможност да спечелят. Например в САЩ през 1992 г. имаше опит доминацията на демократи и републиканци да бъде пробита от Рос Перо, за когото гласуваха милиони американци. Не получи обаче нито един делегат в Избирателната колегия, защото в нито един щат не успя да спечели първо място.

Мажоритарната система облагодетелства политическата сила с най-голям брой победи в отделните състезания дори ако победилата партия е получила по-нисък дял от общите гласове спрямо загубилата. Така Тръмп спечели повече делегати от Хилъри Клинтън през 2016 г., Буш-младши от Ал Гор през 2000 г., а Джъстин Трюдо излезе пред консерваторите на изборите в Канада през 2021 г. В случая обаче ни интересува, че при мажоритарните системи за третия остава много малко и неговата роля в парламента е да подкрепя някоя от големите сили, ако изобщо попадне в него.

Третата система е многопартийната. Тя се среща често в средноевропейски държави, като Белгия и Холандия, но също и в Израел. Най-често причина за нея е пропорционалната избирателна система. Тя позволява доста голям брой политически играчи да попаднат в Народното събрание. Гласът на избирателите по-трудно се губи и съответно те са по-склонни „да го рискуват“. Като резултат в парламента трудно се събира мнозинство и се налагат преговори за коалиция. Те са по-лесни в системи, в които е изградена висока коалиционна култура, и по-трудни, когато има силна поляризация. За съжаление, България е пример точно за последното.

Разбира се, ние сме имали период на тоталитарен режим и затова Аксфорд определя партийната система у нас като „зараждаща се“, но от 2002 г., откогато датира изданието на ползвания от мен учебник, вече минаха доста години. За толкова време би трябвало вече да сме изградили определен профил, въпреки останките от тоталитарните порядки в правораздаването например. Затова можем смело да кажем, че като размер, население и географска принадлежност България е средноевропейска държава и пропорционалната избирателна система е нормална за нея. 

От това следват няколко неща.

Преди всичко, в Народното събрание ще попадат различни партии. Причината се корени не само в разделението ни на различни политически племена (по Димитър Ганев) и във факта, че в България „всяка коза е за свой крак“, а най-вече в обстоятелството, че това състояние е очакваното – и дори желаното – за избирателна система като нашата. Различните групи от населението с различни виждания и интереси получават представителство. Задача на политиците е да намерят работеща формула, за да се съобразят с тях.

У нас обаче го има фактора на поляризацията. Като цяло гласоподавателите очакват от политиците да направят компромиси, но винаги това трябва да сторят тези от другата страна. Техните избраници следва да бъдат непреклонни. Затова и „сглобката“ на ПП–ДБ се прие тежко от избирателите им, независимо че политическите сили в ПП–ДБ са управлявали с почти всички парламентарно представени партии. Затова патриотични партии като ВМРО, НФСБ и „Атака“ изчезват от политическия живот след участие във властта, а „Възраждане“ играят „всичко или нищо“.

Но ако абсолютно всички политически сили предприемат модел на нулев компромис, стигаме до ситуацията с поредица от предсрочни избори и „увиснали“ парламенти, в които правителство така и не може да бъде съставено. Съзнавам, че попадам в хипотезата на закона на Годуин, но при такава ситуация в Германия на власт идват Адолф Хитлер и нацистите.

Така се връщаме на казаното от Асен Василев. 

Възможно ли е ПП–ДБ да спечели 50% от гласовете? На теория – да. Всичко е възможно, ние сме в „тегав“ период в политическо и икономическо отношение. И ако има масово недоволство, което се прелее към тяхната коалиция, а избирателите, които не я подкрепят, останат апатични, хипотетично може и да стане. Строго хипотетично.

На практика обаче не е много вероятно. Мнозина обвиняват еврото, че води до поскъпване, асоциират с него именно либералите от ПП–ДБ и вероятно ще гласуват за патриотичните партии. Други ще кажат: „От какво се оплакват, българите толкова добре не са живели никога“ – и пак ще пуснат бюлетина за ГЕРБ. Трети ще бъдат директно купени, четвърти ще гласуват, притиснати от зависимости, пети – неинформирано или след няколко шарени рийла в TikTok… и т.н.

В резултат по-скоро ще се получи отново пъстър парламент. Защото такава е системата в България – многопартийна и все още демократична. Добре е политиците да се съобразят с това и отсега да мислят за възможни коалиционни партньори. А не да се готвят с оправданията, че предстои още един вот наесен.

Zabbix in 2025: A Year of Growth, Community, and Innovation

Post Syndicated from Michael Kammer original https://blog.zabbix.com/zabbix-in-2025-a-year-of-growth-community-and-innovation/32470/

2025 has been a dynamic and crucial year for Zabbix — marked not just by global events and major releases, but also by meaningful community engagement, an important milestone in our history, new ways of sharing expertise, and headcount growth around the world – all while making sure our product evolves to provide even more value for our valued customers and partners. Let’s dig in!

Celebrating 20 years in business

On April 12, Zabbix officially celebrated its 20th anniversary as a company. It was a time for our entire community to step back, take stock, and imagine what the future might bring as our offices threw some amazing birthday parties to celebrate two decades of growing (and monitoring) together!

“I’m very satisfied with the results we’ve achieved as a company and I’m extremely grateful for our community, customers, and partners – they make everything we do possible.” – Alexei Vladishev, Zabbix Founder and CEO

A new path toward Zabbix expertise

In October, we launched Zabbix Academy, an online learning platform that offers a comprehensive library of interactive courses that are designed to help users master every aspect of Zabbix, on their own time and at their own speed.

Zabbix Academy includes everything from an introduction to open-source monitoring to advanced Zabbix security administration. There’s no need for any prior certification or training, and Zabbix Academy offers certifications and skill assessments aligned with Zabbix standards as well as a flexible pricing model that includes both free and paid courses and webinars, plus the ability to choose either a single standalone course or a yearly subscription.

“Our community is our greatest asset, and we believe that continuous learning is essential for long-term success, and Zabbix Academy is proof of that commitment.” – Kristine Lamberte, Head of Training at Zabbix

Nous sommes Zabbix!

In addition to all the other positive news, 2025 will be remembered as the year we announced the acquisition of our long-term partner IZI-IT and the establishment of Zabbix France, a new regional office dedicated to providing localized support and closer collaboration with French users and enterprises.

Headed by IZI-IT Founder and CEO Steve Destivelle, Zabbix France will leverage France’s strong technology ecosystem, skilled workforce, and strategic location to build a new European hub that will enable faster response times, support compliance with regional business and regulatory expectations, and ultimately boost our brand visibility across Europe.

Home sweet home

2025 also happened to be the year in which Zabbix finally outgrew our long-time Riga location. In September, our search for new premises led us to make the move to a larger and more suitable office space. The new office is spacious, flexible, easily accessible by bicycle or public transport, and features a modern infrastructure that can help us continue growing and competing in the global marketplace.

Building a better product

The big news on the product development front was the release of Zabbix 7.4 in July. Zabbix 7.4 introduces a wide variety of new features that users have requested, while delivering significant UI/UX improvements that make monitoring with Zabbix even more accessible and efficient. Looking forward, our teams are also working hard to bring the next generation of Zabbix features to life, with the following projects in the works:

  • Zabbix 8.0 LTS, which will introduce leading-edge technical features as well as a redesigned user interface with enhanced visualizations for a more intuitive and user-friendly experience.
  • Zabbix Mobile, an official Zabbix Mobile App for iOS and Android that will put instant push notifications, incident management, and seamless collaboration at your fingertips.
  • Zabbix Marketplace, a global platform designed to connect users, partners, and vendors in order to help them exchange information and discover new solutions together.

Growing our community

From major conferences to local meetups and knowledge-sharing events, the global Zabbix ecosystem came together like never before in 2025! Everything we do at Zabbix happens with the knowledge that our community is what sets us apart, which is why we’ll always meet our members wherever they happen to be.

Our global events gave monitoring professionals, partners, and enthusiasts a valuable forum to share their real-world expertise, helping our users keep pace with evolving technologies, strengthening their professional networks, and making sure that community feedback continues to shape our offerings. Some of the highlights included:

  • 12 Zabbix Labs across Latin America, designed to foster vocational education and train specialized professionals who are ready for the professional challenges of the future.
  • 1 regional forum in Mexico City that brought together regional experts to discuss trends, share experiences, and explore how open source tools are changing the technology landscape.
  • 5 conferences (Benelux, Germany, China, Japan, and Latin America) that delivered a unique mix of practical knowledge, direct access to experts, and networking opportunities.
  • Innumerable exhibitions, trade fairs, and expos, which boosted our brand and built relationships.
  • One incredible Zabbix Summit in Riga that brought together hundreds of professionals, developers, partners, and users to share insights, learn from expert talks and workshops, and explore real-world case studies on effective Zabbix use.

Meanwhile, 2025 saw our headcount grow in every one of our global offices, as more and more talented individuals got wind of what we’re doing and chose to be a part of it.

Not to be outdone, our partners team also added 16 Resellers and 16 Certified Partners to our roster of global associates, all while revising and updating our Partner Program to bring Zabbix services to new users in more locations and in additional languages.

Staying safe

Security is not a one-time milestone for Zabbix, but a continuous process. In 2025, we focused on making our security practices more proactive, transparent, and deeply embedded into how we build and operate our products and services.

In 2025 we successfully recertified our ISO/IEC 27001:2022 and ISO/IEC 27017:2015 certifications for another 3 year period. At the same time, our HackerOne bug bounty program continued to be a solid line of defense, as 2025 brought 24 valid submissions that netted $16,700 in bounties.

Furthermore, as Latvia’s only CNA, Zabbix continued to refine its CVE workflows with faster triage and publication timelines, as well as improved vulnerability severity assessment and documentation.

Giving back

During the 2025 holiday season, we continued what may be the most important Zabbix tradition at all – lending our support to local organizations that make a real difference in our communities, including those that provided family support, food relief, access to healthcare and rehabilitation services, and simple holiday joy to senior citizens.

Due in large part to efforts like these, in November Zabbix was named “Enterprise of Riga 2025” in the ICT category – a recognition awarded to the most successful and impactful companies in Riga’s priority sectors. The award highlights not only business results but also contributions to innovation, sustainability, employee well-being, and the growth of the local tech ecosystem.

Looking ahead to 2026

In keeping with our new slogan “Your business works – you know it,” the plan for 2026 and beyond is to evolve from a traditional monitoring tool to a full observability platform, as our Founder and CEO laid out in his keynote speech during Zabbix Summit 2025.

We’re also planning to up our game when it comes to community engagement and training, meaning conferences, meetups, trainings, online events, and global expos that take into account feedback from our community and are increasingly tailored to provide members with what they need most.

With that in mind, we’d like to take this opportunity to thank our amazing global community for everything they did to make 2025 such a success. Whether it was in the form of blog contributions translating documentation, or creating templates and widgets, our community showed up in a big way all throughout the year.

It also goes without saying that we couldn’t have made 2025 the year that it was without our customers, whose trust, collaboration, and commitment to excellence continued to inspire us, drive innovation across everything we do, and allow us to stay open source and innovative.

“Looking ahead, I am genuinely excited about what is coming next in 2026. We have ambitious goals, but I have no doubt whatsoever that together, as one strong, amazing team, we will deliver, grow and continue building something we can all be proud of.” – Alexei Vladishev

The post Zabbix in 2025: A Year of Growth, Community, and Innovation appeared first on Zabbix Blog.

AWS Weekly Roundup: Kiro CLI latest features, AWS European Sovereign Cloud, EC2 X8i instances, and more (January 19, 2026)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-cli-latest-features-aws-european-sovereign-cloud-ec2-x8i-instances-and-more-january-19-2026/

At the end of 2025 I was happy to take a long break to enjoy the incredible summers that the southern hemisphere provides. I’m back and writing my first post in 2026 which also happens to be my last post for the AWS News Blog (more on this later).

The AWS community is starting the year strong with various AWS re:invent re:Caps being hosted around the globe, with some communities already hosting their AWS Community Day events, the AWS Community Day Tel Aviv 2026 was hosted last week.

Last week’s launches
Here are last week’s launches that caught my attention:

  • Kiro CLI latest features – Kiro CLI now has granular controls for web fetch URLs, keyboard shortcuts for your custom agents, enhanced diff views, and much more. With these enhancements, you can now use allowlists or blocklists to restrict which URLs the agent can access, ensure a frictionless experience when working with multiple specialized agents in a single session, to name a few.
  • AWS European Sovereign Cloud – Following an announcement in 2023 of plans to build a new, independent cloud infrastructure, last week we announced the general availability of the AWS European Sovereign Cloud to all customers. The cloud is ready to meet the most stringent sovereignty requirements of European customers with a comprehensive set of AWS services.
  • Amazon EC2 X8i instances – Previously launched in preview at AWS re:Invent 2025, last week we announced the general availability of new memory-optimized Amazon Elastic Compute Cloud (Amazon EC2) X8i instances. These instances are powered by custom Intel Xeon 6 processors with a sustained all-core turbo frequency of 3.9 GHz, available only on AWS. These SAP certified instances deliver the highest performance and fastest memory bandwidth among comparable Intel processors in the cloud.

Additional updates
These projects, blog posts, and news articles also caught my attention:

  • 5 core features in Amazon Quick Suite – AWS VP Agentic AI Swami Sivasubramanian talks about how he uses Amazon Quick Suite for just about everything. In October 2025 we announced Amazon Quick Suite, a new agentic teammate that quickly answers your questions at work and turns insights into actions for you. Amazon Quick Suite has become one of my favorite productivity tools, helping me with my research on various topics in addition to providing me with multiple perspectives on a topic.
  • Deploy AI agents on Amazon Bedrock AgentCore using GitHub Actions – Last year we announced Amazon Bedrock AgentCore, a flexible service that helps you seamlessly create and manage AI agents across different frameworks and models, whether hosted on Amazon Bedrock or other environments. Learn how to use a GitHub Actions workflow to automate the deployment of AI agents on AgentCore Runtime. This approach delivers a scalable solution with enterprise-level security controls, providing complete continuous integration and delivery (CI/CD) automation.

Upcoming AWS events
Join us January 28 or 29 (depending on your time zone) for Best of AWS re:Invent, a free virtual event where we bring you the most impactful announcements and top sessions from AWS re:Invent. Jeff Barr, AWS VP and Chief Evangelist, will share his highlights during the opening session.

There is still time until January 21 to compete for $250,000 in prizes and AWS credits in the Global 10,000 AIdeas Competition (yes, the second letter is an I as in Idea, not an L as in like). No code required yet: simply submit your idea, and if you’re selected as a semifinalist, you’ll build your app using Kiro within AWS Free Tier limits. Beyond the cash prizes and potential featured placement at AWS re:Invent 2026, you’ll gain hands-on experience with next-generation AI tools and connect with innovators globally.

Earlier this month, the 2026 application for the Community Builders program launched. The application is open until January 21st, midnight PST so here’s your last chance to ensure that you don’t miss out.

If you’re interested in these opportunities, join the AWS Builder Center to learn with builders in the AWS community.

With that, I close one of my most meaningful chapters here at AWS. It’s been an absolute pleasure to write for you and I thank you for taking the time to read the work that my team and I pour our absolute hearts into. I’ve grown from the close collaborations with the launch teams and the feedback from all of you. The Sub-Sahara Africa (SSA) community has grown significantly, and I want to dedicate more time focused on this community, I’m still at AWS and I look forward to meeting at an event near you!

Check back next Monday for another Weekly Roundup!

– Veliswa Boya

The end of OzLabs

Post Syndicated from corbet original https://lwn.net/Articles/1055051/

OzLabs is a collection of Australian
free-software developers that was, for most of its history, associated with
IBM. Members of OzLabs have included Hugh Blemings, Michael Ellerman, Ben
Herrenschmidt, Greg Lehey, Paul Mackerras, Martin Pool, Stephen Rothwell,
Rusty Russell, and Andrew Tridgell, among others. The OzLabs “about” page notes that, as
of January 2026, the last remaining OzLabs members have departed IBM.
“This brought to a close the Ozlabs association with IBM“. Thus
ends a quarter-century of development history.

(Thanks to Jon Masters).

Haas: Who contributed to PostgreSQL development in 2025?

Post Syndicated from jzb original https://lwn.net/Articles/1055033/

PostgreSQL contributor Robert Haas has published
a blog post that breaks down code contributions to PostgreSQL in
2025.

I calculate that, in 2025, there were 266 people who were the
principal author of at least one PostgreSQL commit. 66% of the new
lines of code where contributed by one of 26 people, and 90% of the
lines of new code were contributed by one of 67 people.

Contributions to the project seem to be on the upswing; in his analysis
of development in 2024
, there were 229 people who were the primary
authors of a commit, and 66% of new lines of code were contributed by
one of 18 people. The raw
data
is also available.

[$] Task-level io_uring restrictions

Post Syndicated from corbet original https://lwn.net/Articles/1054225/

The io_uring
subsystem
is more than an asynchronous I/O interface for Linux; it is,
for all practical purposes, an independent system-call API. It has enabled
high-performance applications, but it also brings challenges for code built
around classic, Unix-style system calls. For example, the seccomp()
sandboxing mechanism does not work with it, causing applications using
seccomp() to disable io_uring outright. Io_uring maintainer Jens
Axboe is seeking to improve that situation with a rapidly evolving patch
series adding a new restrictive mechanism to that subsystem.

Wine 11.0 released

Post Syndicated from jzb original https://lwn.net/Articles/1055001/

Version
11.0
of the Wine Windows compatibility layer is out. “This
release represents a year of development effort, around 6,300
individual changes, and more than 600 bug fixes.
” The most notable
changes in this release are support for the NTSync Linux kernel module
(when available), and the completion of the Windows 32-bit on Windows 64-bit (WoW64) architecture that was announced as experimental in Wine 9.0.

How we mitigated a vulnerability in Cloudflare’s ACME validation logic

Post Syndicated from Hrushikesh Deshpande original https://blog.cloudflare.com/acme-path-vulnerability/

On October 13, 2025, security researchers from FearsOff identified and reported a vulnerability in Cloudflare’s ACME (Automatic Certificate Management Environment) validation logic that disabled some of the WAF features on specific ACME-related paths. The vulnerability was reported and validated through Cloudflare’s bug bounty program.

The vulnerability was rooted in how our edge network processed requests destined for the ACME HTTP-01 challenge path (/.well-known/acme-challenge/*).

Here, we’ll briefly explain how this protocol works and the action we took to address the vulnerability. 

Cloudflare has patched this vulnerability and there is no action necessary for Cloudflare customers. We are not aware of any malicious actor abusing this vulnerability.

How ACME works to validate certificates

ACME is a protocol used to automate the issuance, renewal, and revocation of SSL/TLS certificates. When an HTTP-01 challenge is used to validate domain ownership, a Certificate Authority (CA) will expect to find a validation token at the HTTP path following the format of http://{customer domain}/.well-known/acme-challenge/{token value}. 

If this challenge is used by a certificate order managed by Cloudflare, then Cloudflare will respond on this path and provide the token provided by the CA to the caller. If the token provided does not correlate to a Cloudflare managed order, then this request would be passed on to the customer origin, since they may be attempting to complete domain validation as a part of some other system. Check out the flow below for more details — other use cases are discussed later in the blog post.


The underlying logic flaw 

Certain requests to /.well-known/acme-challenge/* would cause the logic serving ACME challenge tokens to disable WAF features on a challenge request, and allow the challenge request to continue to the origin when it should have been blocked.

Previously, when Cloudflare was serving a HTTP-01 challenge token, if the path requested by the caller matched a token for an active challenge in our system, the logic serving an ACME challenge token would disable WAF features, since Cloudflare would be directly serving the response. This is done because those features can interfere with the CA’s ability to validate the token values and would cause failures with automated certificate orders and renewals.

However, in the scenario that the token used was associated with a different zone and not directly managed by Cloudflare, the request would be allowed to proceed onto the customer origin without further processing by WAF rulesets.

How we mitigated this vulnerability

To mitigate this issue, a code change was released. This code change only allows the set of security features to be disabled in the event that the request matches a valid ACME HTTP-01 challenge token for the hostname. In that case, Cloudflare has a challenge response to serve back.

Cloudflare customers are protected

As we noted above, Cloudflare has patched this vulnerability and Cloudflare customers do not need to take any action. In addition, we are not aware of any malicious actor abusing this vulnerability.

Moving quickly with vulnerability transparency

As always, we thank the external researchers for responsibly disclosing this vulnerability. We encourage the Cloudflare community to submit any identified vulnerabilities to help us continually improve the security posture of our products and platform. 

We also recognize that the trust you place in us is paramount to the success of your infrastructure on Cloudflare. We consider these vulnerabilities with the utmost concern and will continue to do everything in our power to mitigate impact. We deeply appreciate your continued trust in our platform and remain committed not only to prioritizing security in all we do, but also acting swiftly and transparently whenever an issue does arise. 

The collective thoughts of the interwebz