Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=UvGxnt_f-MA
New delegation for Debian’s data protection team
Post Syndicated from jzb original https://lwn.net/Articles/1058663/
Debian Project Leader (DPL) Andreas Tille has announced
a new delegation for Debian’s data projection team:
Following the end of the previous delegation, Debian was left
without an active Data Protection team. This situation has
understandably drawn external attention and highlighted the importance
of having a clearly identified point of contact for data protection
matters within the project.I am therefore very pleased to announce that new volunteers have
stepped forward, allowing us to re-establish the Debian Data
Protection team with a fresh delegation.
Tille had put out a call for
volunteers in January after all previous members of the team had
stepped down. He has appointed Aigars Mahinovs, Andrew M.A. Cater,
Bart Martens, Emmanuel Arias, Gunnar Wolf, Kiran S Kunjumon, and Salvo
Tomaselli as the new members of the team. The team provides a central
coordination and advisory function around Debian’s data handling,
retention, dealing with deletion requests, and more.
[$] The first half of the 7.0 merge window
Post Syndicated from daroc original https://lwn.net/Articles/1057769/
The merge window for Linux 7.0 has opened, and with it
comes a number of interesting improvements and enhancements. At the time of
writing, there have been 7,695 non-merge commits accepted. The 7.0 release is
not special,
according to the kernel’s versioning scheme — just the release
that comes after 6.19. Humans love symbolism and round numbers, though, so it
may feel like something of a milestone.
Projectors vs $50,000 MicroLED? Don’t Turn the Lights On.
Post Syndicated from The Hook Up original https://www.youtube.com/watch?v=Xu9vPrU5hiQ
[$] Open-source mapping for disaster response
Post Syndicated from jzb original https://lwn.net/Articles/1057691/
At FOSDEM 2026 Petya
Kangalova, a senior tech partnership and engagement manager for the Humanitarian OpenStreetMap
Team (HOT) spoke about how
the project helps people map their surroundings to assist in
disaster response and humanitarian aid. The project has
developed a stack of technology to help volunteers collectively map an
area and add in local knowledge metadata. “One of the core things
.”
that we believe is that when we speak about disaster response or
people having access to data is that they really need accessible
technology that’s free and open for anyone to use
Security updates for Friday
Post Syndicated from jzb original https://lwn.net/Articles/1058642/
Security updates have been issued by AlmaLinux (firefox, gcc-toolset-14-binutils, nodejs:20, nodejs:22, nodejs:24, php:7.4, and python3.12), Debian (haproxy, nginx, postgresql-15, and postgresql-17), Fedora (libssh), Oracle (glib2, libsoup, nodejs:20, nodejs:22, and php:7.4), SUSE (assimp, gnutls, helm, kernel, kubevirt, virt-api-container, virt-controller-container, virt-exportproxy-container, virt-exportserver-container, virt-handler-container, virt-launcher-container, virt-libguestfs-t, libmunge2, libsodium, libsoup, micropython, munge, openCryptoki, python-azure-core, rust-keylime, rustup, sccache, snpguest, tcpreplay, xorg-x11-server, xrdp, and zabbix), and Ubuntu (dnsdist, dotnet8, dotnet9, dotnet10, haproxy, libpng1.6, linux-aws-5.15, linux-azure, linux-azure-fips, linux-oracle, linux-oracle-5.4, munge, nginx, and node-dottie).
The Laws of Physics Don’t Apply to Ilia Malinin
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/IpJWVkcOkeE
The "Coolidge Cruisers"
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=ppQoDBooSQ4
Три стъпки на Андрей Гюров
Post Syndicated from Емилия Милчева original https://www.toest.bg/tri-stupki-na-andrey-gyurov/

Какъв пост ще заеме Андрей Гюров при едно редовно правителство, след като приключи с дейността си като служебен премиер, е още рано да се каже. Сигурно е, че ще продължи, засега на преден план е усмивката му, след като президентката Илияна Йотова го номинира за служебен министър-председател.
Безспорно Гюров е доволен от новото стъпало в кариерата си, след като беше депутат, председател на парламентарната група на „Продължаваме промяната“, и подуправител на Българската народна банка за управление „Емисионно“.
„Не съм член на „Продължаваме промяната“, заяви обаче Гюров, след като получи папката с мандата за съставяне на правителство. Тази седмица се чуха прогнози, че може да мине и към проекта на доскорошния президент Румен Радев.
Ако г-н Гюров се справи с провеждането на изборите, мисля, че той може да бъде припознат от новата партия на Румен Радев,
заяви по БНТ политологът Теодор Славев.
Обаятелен и владеещ чужди езици, той е много различен от председателя на Сметната палата Димитър Главчев, заявил готовност да потрети на „Дондуков“ 1.
Нов и.ф. главен прокурор?
Сега Гюров с облекчение ще напусне БНБ, където изкара една година, а е в неплатен отпуск от година и седем месеца. Причината е правният казус, заплел се, след като закритата вече Антикорупционна комисия установи несъвместимост заради участието му като съдружник в „Йонтех Инженеринг“ ООД и в управата на две сдружения с нестопанска цел. БНБ опита да го освободи, той обжалва, а Върховният административен съд спря делото и по искане на защитата на Гюров се обърна към Съда на ЕС за тълкуване по казуса, след което ВАС ще се произнесе. Развитието на тези събития няма да попречи на Андрей Гюров да изпълнява функциите на служебен премиер. При позитивен за него изход от съдебното дело ще получи и възнагражденията си от БНБ за периода на отстраняване.
Следващата седмица той ще представи състава на кабинета си и се заема с управлението, но най-напред с главния прокурор, МВР и вероятно със службите. Андрей Гюров вече отбеляза колко важна е ролята на бъдещите министри на вътрешните работи и на правосъдието. За първия смята да е човек от системата, а за правосъдния – че трябва да се заеме със смяната на и.ф. главен прокурор Борислав Сарафов, чиято легитимност се оспорва не от вчера.
ПП–ДБ отдавна настояват правосъдният министър да предложи на прокурорската колегия на ВСС да назначи друг изпълняващ длъжността вместо Сарафов. Разбира се, кадровиците може и да не се вслушат, но кой знае… Това е в правомощията на министъра на правосъдието, но настоящият – Георги Георгиев, така и не постави за обсъждане подобна точка в дневния ред на ВСС.
Но Сарафов би могъл да изненада и сам да се оттегли. Със сигурност си дава сметка, че времето му в това кресло е изтекло. Главните прокурори в България винаги са функция на политическите трусове – справка: предшественикът му Иван Гешев беше освободен в разгара на политическите договорки за т.нар. сглобка между ГЕРБ–СДС и ПП–ДБ (накрая и ДПС на Делян Пеевски).
Амбицията на Румен Радев и на кръга около него е ясна – да имат тежката дума при избора на следващия обвинител №1. Неизвестното е с кой коалиционен партньор (или партньори) ще споделят новия състав на ВСС, който да направи възможен този избор. Преди обаче да се стигне дотам, има по-близка и не по-малко важна задача – провеждането на изборите.
МВР, службите, изборите
МВР отново ще се разпердушинва, за да се демонстрират контрол върху купения вот и мобилизация, която да респектира. Както преди всички нови избори ще се сменят шефове на областни дирекции.
Паралелно с това вниманието ще бъде насочено и към службите за сигурност. Там премиерът има по-голяма свобода на действие чрез Министерския съвет, особено по отношение на координацията и кадровите решения, когато законът го допуска.
Какво може да направи Гюров по отношение на службата, около която най-много се шуми в последните дни – Държавна агенция „Национална сигурност“?
Миналата есен мнозинството, което доминираше в 51-вия парламент – ГЕРБ, ДПС – Ново начало, БСП и „Има такъв народ“, отнеха на президента думата при назначаването на шефа на ДАНС. Неговият указ вече не е необходим, решава парламентът.
В момента ДАНС е с и.ф. шеф Деньо Денев, свързван с Пеевски. Денев има двама заместници, креслото на третия е празно. Има спекулации, че парламентът може да го запълни, преди депутатите да излязат в предизборна кампания. Идеята е, че този трети заместник би могъл да стане и следващият и.ф. „титуляр“. По закон заместник-председателите на ДАНС се определят с решение на Министерския съвет за срок от 5 години по предложение на председателя на Агенцията.
Интересна подробност е, че макар кабинетът на Росен Желязков да внесе в парламента предложение Денев да бъде избран за титуляр на поста и даже беше изслушан, то така и не влезе в дневния ред.
Правителството на Гюров няма да е първото, което ще прави промени в службите. През 2024 г. служебният кабинет на свързания с ГЕРБ Димитър Главчев освободи от ДАНС един от заместник-председателите – Петър Петров, бивш депутат от ПП.
Предишният шеф на ДАНС Пламен Тончев беше избор на президента, тъй като получи поста при един от служебните му кабинети. По предложение на служебното правителство на Стефан Янев през 2021 г. беше освободен Димитър Георгиев и назначен Тончев, ръководил дотогава регионалното звено на Агенцията във Враца.
Случаят „Петрохан“
В контекста на трагедията с шестте трупа от случая „Петрохан“ промените в службите изглеждат неизбежни. Откритите тела на мъртвите „рейнджъри“ и свързването им с близки до ПП–ДБ фигури взриви и обществото, и политиците, поляризирайки всички оценки.
За Гюров това е двойно предизвикателство. От една страна, всяка смяна в ДАНС или в ръководството на МВР ще бъде тълкувана политически – като опит за овладяване на системата преди изборите. От друга страна, липсата на реакция би изглеждала като съгласие със статуквото. Балансът между демонстрация на контрол и избягване на политическа чистка ще бъде доста крехък.
Представянето на служебното правителство ще съвпадне с датата 19 февруари, когато американският президент Доналд Тръмп свиква първото заседание на Съвета за мир. България и Унгария са единствените страни членки на ЕС сред учредителите и засега липсва яснота ще има ли представител на България. Правителството на Желязков остави ратификацията на договора за следващия парламент.
Това, върху което се обединихме с Президентството, е, че в служебния кабинет не трябва да има хора на конци, сламени фигури, заплюти територии. Ще работим по най-важните задачи пред държавата, за да има едно плавно предаване на управлението към следващото мнозинство, да се справим с всички кризи, които биха се изправили пред нас, и да осигурим спокойствие.
Осигуряването на спокойствие обаче изглежда трудно постижимо на фона на развихрилите се страсти покрай случая „Петрохан“. Истерията около трагедията достигна такива върхове, че общественото внимание е изцяло погълнато от обвинения, спекулации, лъжи и опити за окалване. На този фон прави впечатление мълчанието на двамата влиятелни политически играчи, срещу които бяха декемврийските протести – Бойко Борисов и Делян Пеевски. Мълчание продължително и многозначително, което често означава изчакване на удобния момент, а не липса на позиция.
В такава среда Андрей Гюров ще трябва да доказва, че служебният кабинет не е временен буфер, а гарант за стабилност. Скоро ще се разбере.
Гласовете на Америка – брой 12
Post Syndicated from Йоанна Елми original https://www.toest.bg/glasovete-na-amerika-broy-12/

Rapid-fire означава буквално „стрелба с висока скорост, огромна бързина“ – на български имаме прилагателното скорострелен. Rapid-fire могат да бъдат например шеги на комедиант, които идват една след друга; такива могат да бъдат и въпроси в съда. Rapid-fire са и новините, които произвежда Америка – rapid-fire е и нейният президент, за когото дори потребителите в консервативния събредит понякога казват, че трябва да говори по-малко и да работи повече (защото и без това говори глупости – пак думи на потребителите).
Вицепрезидентът на САЩ Джей Ди Ванс беше освиркан по време на зимните олимпийски игри в Милано.
По-рано този месец в града имаше протести срещу присъствието на имиграционната полиция на САЩ в Италия, която според Reuters е изпратена, за да „защитава американците“. Официалната позиция на италианската власт и на Олимпийския и параолимпийски комитет на САЩ е, че такива агенти на имиграционната полиция (ICE) няма; има единствено оперативни служители на Департамента по държавна сигурност, базирани в американските дипломатически мисии в Италия.
Едва ли някой може да обвини имиграционните, че имат нужда от разнообразяване в Италия след убийствата на Рене Гуд и Алекс Прети. По време на изслушването по двата случая във вторник Тод Лайънс, настоящият ръководител на ICE, както и Родни Скот, шефът на американската гранична полиция, отказаха да отговарят на въпроси за убийството на двамата американски граждани. Лайънс отказа да се извини от името на администрацията на Тръмп, която нарече жертвите „терористи“.
На паралелната армия на САЩ вероятно ще ѝ бъде необходимо повече от едни зимни олимпийски игри, за да отмори и да се подготви за „национализацията на изборите“, за която призова президентът Тръмп. Разбира се, симпатизантите на Тръмп ще кажат например, че той просто се шегува и дразни либералите, които, както винаги, му се връзват, защото са точно толкова глупави.
Дали това е така, или не, няма да коментираме – факт е, че през изминалите седмици агенти на ФБР иззеха бюлетини и документи за изборите през 2020 г. от окръг Фултън, Джорджия. Президентът и симпатизантите му твърдят, въпреки наличните доказателства, че именно там е имало изборни измами, които са му коствали поста. Както всеки съвестен лидер, президентът Тръмп разговарял с агентите на ФБР по време на акцията – изразил благодарността си и им направил комплименти. Какво по-нормално от това в крайна сметка?
Напълно в реда на нещата е и изискването на Департамента по правосъдието от множество щати, сред които и Минесота, да предадат избирателните си списъци на федералното правителство, тъй като администрацията на Тръмп се опитва да създаде федерални (национални) избирателни списъци. Според принципите на разделението на властите в САЩ изборите се организират на местно, щатско ниво. Но едва ли има по-подходящ пример за спазването на десния принцип за „малка държава“ и „права на щатите“ (states’ rights) от желанието на президента да национализира изборите. В крайна сметка през март миналата година същият президент подписа указ, с който се опита да направи мащабни промени в изборния кодекс – повечето от тях на този етап са спрени или напълно оборени в съда. В миналото президентът Тръмп е публикувал в социалните мрежи, че иска да ограничи гласуването по пощата, както и изборните машини. Ако сте се объркали дали става въпрос за САЩ, или за България, не сте единствени.
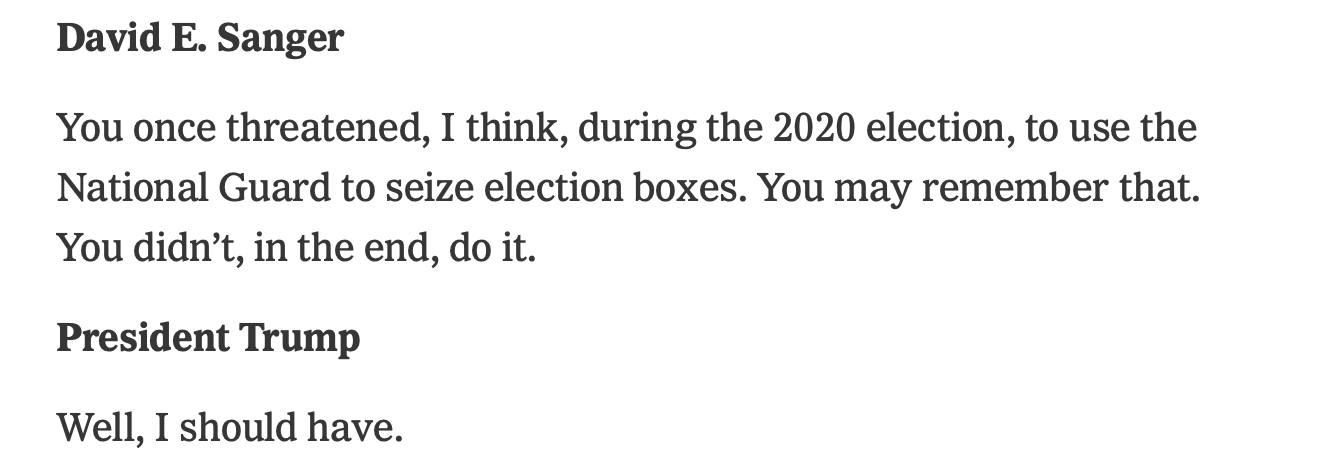
Преначертаването на картите на избирателните райони, което е традиция в САЩ от дълги години насам и се практикува и от двете партии, е в своя апогей. В интервю за The New York Times пък президентът заяви, че е съжалил, че не е пратил националната гвардия да конфискува машините след изборите през 2020 г. Лидерът на най-мощната държава, на свободния свят и т.н. в крайна сметка просто се шегува. Ха-ха-ха!
Междувременно администрацията празнува премахването на почти всички държавни регулации, свързани с климата. Успехът е дело на хора, които са възмутени от „климатичният алармизъм“ и „ленинисткия заговор“ на опазващото климата законодателство. Вероятно именно заради подобни заключения всяка втора статия в The New York Times съдържа някаква вариация на изречението
В света има научен консенсус, че въглеродният диоксид, метанът и други парникови газове опасно загряват планетата и стават причина за появата на суперурагани, суши, горещи вълни и повишаване на нивото на Световния океан.
Нещо подобно на надписите върху етикетите на дрехите, които ни предупреждават да не ги ядем, да не ги палим и да не използваме ръкавите им, за да се обесим например. Умните политици в крайна сметка са отражение на умните си избиратели – така работи представителната демокрация, ако все още изобщо можем да говорим за такава.
А и конспирациите престават да бъдат интересни, когато се окажат истина. Кой да знае това по-добре от световния политически и икономически елит, който с години се е събирал на купони с малолетни и непълнолетни в именията на осъден сексуален престъпник. Три милиона страници, 180 000 изображения и 2000 видеоклипа бяха пуснати шест седмици след крайния срок, обявен от закона, както и след много закани за превземане на Гренландия (Какво стана с Гренландия? Кой изобщо помни Гренландия?). Разбира се, както след всеки купон, накрая всички отричат, че са били там. Сигурно е, че президентът на САЩ никога не е бил там, разбира се. Разбира се.
Гласовете на Америка – брой 11
Какво стана във Венецуела и ще продължи ли да се случва и на други места по света? В първия за годината брой на бюлетина, посветен на Щатите, Йоанна Елми прави анализ на събитията от 3 януари и на това, което стои зад тях.
 Йоанна Елми
Да се върнем на гейовете, имигрантите и цветнокожите, които, както добре знаем, са виновни за всичките мъки на човешкия род и най-вече на средностатистическия републикански избирател, който се отъждествява повече с големите богати мъже, концентриращи богатство и ресурси, отколкото със съседите си, които – ако не дай си боже не мислят като него – са розови либерали, марксисти, комунисти, национални предатели, терористи и т.н.
Флагът на прайда бе премахнат от монумента в Стоунуол, Ню Йорк. Мястото е част от мрежата от национални паркове и исторически паметници в САЩ. Стоунуолските бунтове са сблъсъците между хора от ЛГБТ общността и нюйоркската полиция през 1969 г. и се смятат за повратната точка в борбата на хората с различна сексуална ориентация за равни права.
Премахнати бяха и табелите с историческа информация за робството в САЩ от Филаделфия, където е живял първият президент – Джордж Вашингтон, който е бил и робовладелец. Причината? „Антиамериканска идеология“, разбира се.
Над 18 000 жалби са постъпили в съдебната система на САЩ от имигранти, които твърдят, че са били обект на незаконно и неправомерно задържане. Екип от журналисти „влезе“ в лагера за задържани в Дили, Тексас, и проведе видеоразговори със задържаните деца.
Важното е, че американците са в безопасност – най-вече от реалността, която не им допада. Консервативното движение дори измисли алтернатива на легендарното шоу в полувремето на „Супербоул“. Така някой може би е слушал Кид Рок и е гледал Ерика Кърк, а е пропуснал рекламата, която взриви интернет. Камерите Ring, работещи на принципа на система за разпознаване на сладки кученца (и човешки лица), ви заснемат и разпознават при всяко преминаване, благодарение на което, радват се потребителите, малката държава ще може да става все по-малка – Ring предоставя данни на местната полиция, която потенциално си сътрудничи с федералната власт и ICE.
What this ad doesn’t show: Ring also rolled out facial recognition for humans. I wrote to them months ago about this. Their answer? They won’t ask for your consent.
This definitely isn’t about dogs—it’s about mass surveillance. https://t.co/bncjffU3DZ
— Ed Markey (@SenMarkey) February 9, 2026
Разбира се, повод за притеснения няма и това може би просто е поредната буря в чаша вода – все пак Ring е собственост на Amazon и Джеф Безос, който предприе мащабни съкращения в The Washington Post, като кореспондентът в Украйна например научи, че вече не е кореспондент в Украйна, докато беше на терен в Украйна. Когато подобни мощни технологии са собственост на филантропи и трезвомислещи хора, повод за притеснения най-общо няма. Така че стига с либералната истерия? Все едно когато Мъск купи Twitter и всички предупреждаваха, че социалната мрежа ще се превърне в кошер на пропаганда, дезинформация и измамни реклами, това се случи.
А като стана дума за Илън Мъск, който щеше да направи американските институции ефективни отново, само че му стана скучно, тази седмица той призна, че в крайна сметка няма да стигне до Марс, а само до Луната. Ето един клип на Мъск, който обещава автономни тесли до следващата година:
In 2012, Musk first claimed he would put a man on Mars within about 10 years. Today, after some solid progress, he says the goal is just 20 years away.
To those looking to invest into his next big hype, here's 10 years of him promising fully self-driving Teslas by next year: pic.twitter.com/kt7hPU5y6F
— Daractenus (@Daractenus) February 9, 2026
Институциите може да не са ефективни вече, но Америка със сигурност вече е велика.
Големите пари от съвременната икономика отиват при капитала, не при работниците
Това не е подглава от „Капиталът“ на Маркс, а заглавие в десния The Wall Street Journal. Джърнъл, джърнъл, колко пък да е джърнъл – ще го направим и него на алтернативен вестник, както направихме алтернативно шоу и както опраскахме и The Washington Post.
Economy so bad that the WSJ is running Marxist headlines pic.twitter.com/qs43ZjIKGf
— Heidi N. Moore (@moorehn) February 10, 2026
И колкото и да не съм вярвала, че някога ще го кажа, Америка върви толкова на зле, че дори и либертарианците започват да звучат разумно. В пространно есе за The New York Times главният редактор на водещото либертарианско списание Reason предупреждава за злоупотребата с власт – която е възможна само след злоупотреба с истината – и подчертава, че въпреки бомбастичните намерения и заявки на администрацията на Тръмп резултатите са повече от плачевни от гледна точка на свободата, справедливостта и изобщо на цялото величие на въпросната Америка.
Редакцията на The New York Times пък е публикувала доста интересно есе за проблемите след легализирането на марихуаната: употребата на веществото е скочила главоломно, причинявайки проблеми със зависимостта и различни свързани заболявания. Редакцията не призовава към повторна забрана, но отчита, че експериментът с легализацията може би има нужда от корекция.
Този rapid-fire може да продължи до безкрай и вероятно поне още три години, докато трупът на Велика Америка не изкърви. Днес обаче бюлетинът ще се вмести в рамките си – понякога голямата история, която може би носи някакво успокоение, трябва да остане настрана и просто да обърнем внимание на историята, която пишем в настоящето. За мен все още е трудно да повярвам, че изборът на толкова хора е да пишат именно тази история – колкото и да разбирам сложността и пластовете на настоящето, както и какво формира възгледите на всеки отделен човек.
Но може би именно това е най-ужасяващото: че най-немислимата жестокост и абсурди се поддържат не от чудовища, а от хора, които са също като нас. Затова ви оставям с един скорошен скеч на Saturday Night Live – не се засмях, но поне се усмихнах. Някои дни и това е нещо.
Абонирайте се, за да получавате този бюлетин на електронната си поща в момента, в който излезе!
Вече сте регистриран потребител на Toest.bg? Може директно от настройките на бюлетините в своя профил да изберете „Гласовете на Америка“ или да натиснете бутона по-долу:
Още нямате профил в Toest.bg? Регистрирайте се само с няколко клика:
Scaling LLM Post-Training at Netflix
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/scaling-llm-post-training-at-netflix-0046f8790194
Baolin Li, Lingyi Liu, Binh Tang, Shaojing Li
Introduction
Pre-training gives Large Language Models (LLMs) broad linguistic ability and general world knowledge, but post-training is the phase that actually aligns them to concrete intents, domain constraints, and the reliability requirements of production environments. At Netflix, we are exploring how LLMs can enable new member experiences across recommendation, personalization, and search, which requires adapting generic foundation models so they can better reflect our catalog and the nuances of member interaction histories. At Netflix scale, post-training quickly becomes an engineering problem as much as a modeling one: building and operating complex data pipelines, coordinating distributed state across multi-node GPU clusters, and orchestrating workflows that interleave training and inference. This blog describes the architecture and engineering philosophy of our internal Post-Training Framework, built by the AI Platform team to hide infrastructure complexity so researchers and model developers can focus on model innovation — not distributed systems plumbing.
A Model Developer’s Post-Training Journey
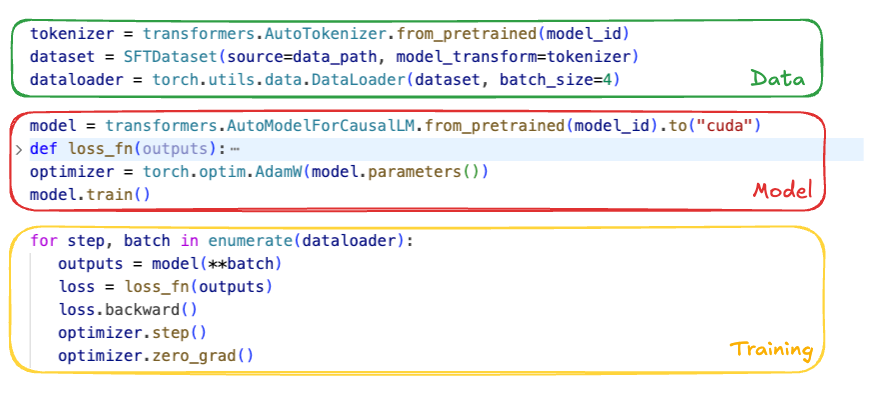
Post-training often starts deceptively simply: curate proprietary domain data, load an open-weight model from Hugging Face, and iterate batches through it. At the experimentation scale, that’s a few lines of code. But when fine-tuning production-grade LLMs at scale, the gap between “running a script” and “robust post-training” becomes an abyss of engineering edge cases.
Getting the data right
On paper, post-training is straightforward: choose a tokenizer, preprocess the dataset, and build a dataloader. In practice, data preparation is where things break. High-quality post-training — instruction following, multi-turn dialogue, Chain-of-Thought — depends on precisely controlling which tokens contribute to the loss. Hugging Face chat templates serialize conversations, but don’t specify what to train on versus ignore. The pipeline must apply explicit loss masking so only assistant tokens are optimized; otherwise the model learns from prompts and other non-target text, degrading quality.
Variable sequence length is another pitfall. Padding within a batch can waste compute, and uneven shapes across FSDP workers can cause GPU synchronization overhead. A more GPU-efficient approach is to pack multiple samples into fixed-length sequences and use a “document mask” to prevent cross-attention across samples, reducing padding and keeping shapes consistent.
Setting up the model
Loading an open-source checkpoint sounds simple until the model no longer fits on one GPU. At that point you need a sharding strategy (e.g., FSDP, TP) and must load partial weights directly onto the device mesh to avoid ever materializing the full model on a single device.
After loading, you still need to make the model trainable: choose full fine-tuning vs. LoRA, and apply optimizations like activation checkpointing, compilation, and correct precision settings (often subtle for RL, where rollout and policy precision must align). Large vocabularies (>128k) add a further memory trap: logits are [batch, seq_len, vocab] and can spike peak memory. Common mitigations include dropping ignored tokens before projection and computing logits/loss in chunks along the sequence dimension.
Starting the training
Even with data and models ready, production training is not a simple “for loop”. The system must support everything from SFT’s forward/backward pass to on-policy RL workflows that interleave rollout generation, reward/reference inference, and policy updates.
At Netflix scale, training runs as a distributed job. We use Ray to orchestrate workflows via actors, decoupling modeling logic from hardware. Robust runs also require experiment tracking (model quality metrics like loss and efficiency metrics like MFU) and fault tolerance via standardized checkpoints to resume cleanly after failures.
These challenges motivate a post-training framework that lets developers focus on modeling rather than distributed systems and operational details.
The Netflix Post-Training Framework
We built Netflix’s LLM post-training framework so Netflix model developers can turn ideas like those in Figure 1 into scalable, robust training jobs. It addresses the engineering hurdles described above, and also constraints that are specific to the Netflix ecosystem. Existing tools (e.g., Thinking Machines’ Tinker) work well for standard chat and instruction-tuning, but their structure can limit deeper experimentation. In contrast, our internal use cases often require architectural variation (for example, customizing output projection heads for task-specific objectives), expanded or nonstandard vocabularies driven by semantic IDs or special tokens, and even transformer models pre-trained from scratch on domain-specific, non-natural-language sequences. Supporting this range requires a framework that prioritizes flexibility and extensibility over a fixed fine-tuning paradigm.
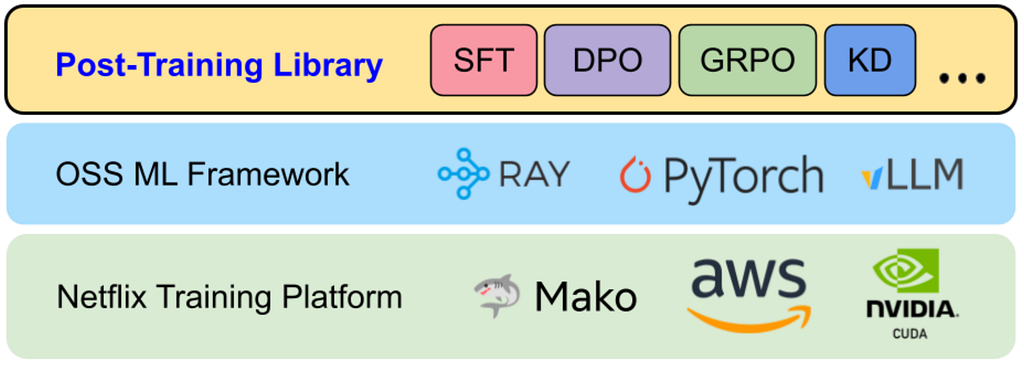
Figure 2 shows the end-to-end stack from infrastructure to trained models. At the base is Mako, Netflix’s internal ML compute platform, which provisions GPUs on AWS. On top of Mako, we run robust open-source components — PyTorch, Ray, and vLLM — largely out of the box. Our post-training framework sits above these foundations as a library: it provides reusable utilities and standardized training recipes for common workflows such as Supervised Fine-Tuning (SFT), Direct Preference Optimization (DPO), Reinforcement Learning (RL), and Knowledge Distillation. Users typically express jobs as configuration files that select a recipe and plug in task-specific components.
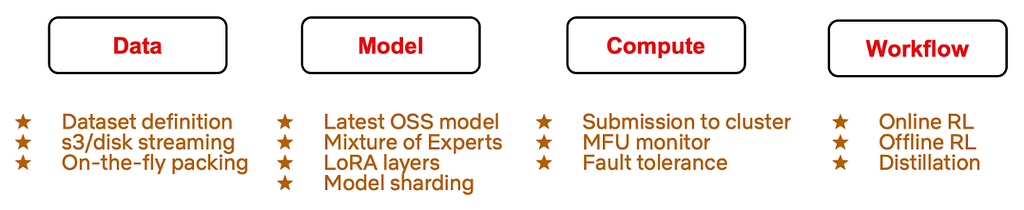
Figure 3 summarizes the modular components we built to reduce complexity across four dimensions. As with most ML systems, training success hinges on three pillars — Data, Model, and Compute — and the rise of RL fine-tuning adds a fourth pillar: Workflow, to support multi-stage execution patterns that don’t fit a simple training loop. Below, we detail the specific abstractions and features the framework provides for each of these dimensions:
- Data: Dataset abstractions for SFT, reward modeling, and RL; high-throughput streaming from cloud and disk for datasets that exceed local storage; and asynchronous, on-the-fly sequence packing to overlap CPU-heavy packing with GPU execution and reduce idle time.
- Model: Support for modern architectures (e.g., Qwen3, Gemma3) and Mixture-of-Experts variants (e.g., Qwen3 MoE, GPT-OSS); LoRA integrated into model definitions; and high-level sharding APIs so developers can distribute large models across device meshes without writing low-level distributed code.
- Compute: A unified job submission interface that scales from a single node to hundreds of GPUs; MFU (Model FLOPS Utilization) monitoring that remains accurate under custom architectures and LoRA; and comprehensive checkpointing (states of trained parameters, optimizer, dataloader, data mixer, etc.) to enable exact resumption after interruptions.
- Workflow: Support for training paradigms beyond SFT, including complex online RL. In particular, we extend Single Program, Multiple Data (SPMD) style SFT workloads to run online RL with a hybrid single-controller + SPMD execution model, which we’ll describe next.
Today, this framework supports research use cases ranging from post-training large-scale foundation models to fine-tuning specialized expert models. By standardizing these workflows, we’ve lowered the barrier for teams to experiment with advanced techniques and iterate more quickly.
Learnings from Building the Post-Training Framework
Building a system of this scope wasn’t a linear implementation exercise. It meant tracking a fast-moving open-source ecosystem, chasing down failure modes that only appear under distributed load, and repeatedly revisiting architectural decisions as the post-training frontier shifted. Below are three engineering learnings and best practices that shaped the framework.
Scaling from SFT to RL
We initially designed the library around Supervised Fine-Tuning (SFT): relatively static data flow, a single training loop, and a Single Program, Multiple Data (SPMD) execution model. That assumption stopped holding in 2025. With DeepSeek-R1 and the broader adoption of efficient on-policy RL methods like GRPO, SFT became table stakes rather than the finish line. Staying close to the frontier required infrastructure that could move from “offline training loop” to “multi-stage, on-policy orchestration.”
SFT’s learning signal is dense and immediate: for each token position we compute logits over the full vocabulary and backpropagate a differentiable loss. Infrastructure-wise, this looks a lot like pre-training and maps cleanly to SPMD — every GPU worker runs the same step function over a different shard of data, synchronizing through Pytorch distributed primitives.
On-policy RL changes the shape of the system. The learning signal is typically sparse and delayed (e.g., a scalar reward at the end of an episode), and the training step depends on data generated by the current policy. Individual sub-stages — policy updates, rollout generation, reference model inference, reward model scoring — can each be implemented as SPMD workloads, but the end-to-end algorithm needs explicit coordination: you’re constantly handing off artifacts (prompts, sampled trajectories, rewards, advantages) across stages and synchronizing their lifecycle.
In our original SFT architecture, the driver node was intentionally “thin”: it launched N identical Ray actors, each encapsulating the full training loop, and scaling meant launching more identical workers. That model breaks down for RL. RL required us to decompose the system into distinct roles — Policy, Rollout Workers, Reward Model, Reference Model, etc. — and evolve the driver into an active controller that encodes the control plane: when to generate rollouts, how to batch and score them, when to trigger optimization, and how to manage cluster resources across phases.
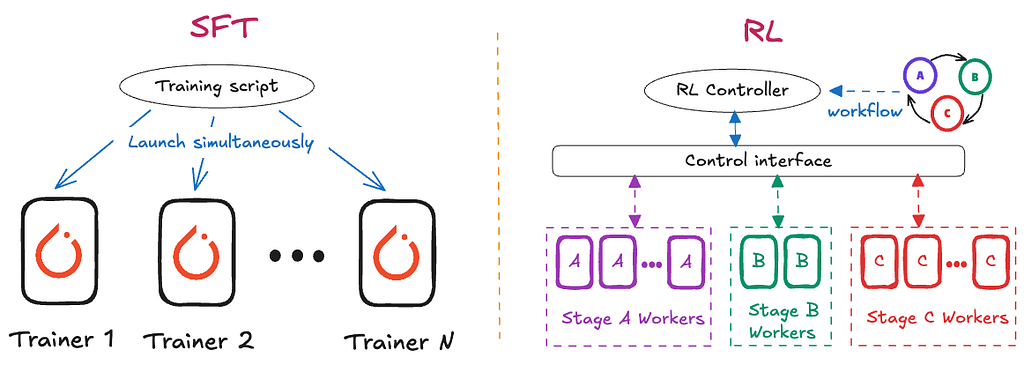
Figure 4 highlights this shift. To add RL support without reinventing distributed orchestration from scratch, we integrated the core infrastructure from the open-source Verl library to manage Ray actor lifecycle and GPU resource allocation. Leveraging Verl’s backend let us focus on the “modeling surface area” — our Data/Model/Compute abstractions and internal optimizations — while keeping orchestration concerns decoupled. The result is a hybrid design: a unified user interface where developers can move between SFT and RL workflows without adopting an entirely different mental model or API set.
Hugging Face-Centric Experience
The Hugging Face Hub has effectively become the default distribution channel for open-weight LLMs, tokenizers, and configs. We designed the framework to stay close to that ecosystem rather than creating an isolated internal standard. Even when we use optimized internal model representations for speed, we load and save checkpoints in standard Hugging Face formats. This avoids “walled garden” friction and lets teams pull in new architectures, weights, and tokenizers quickly.
This philosophy also shaped our tokenizer story. Early on, we bound directly to low-level tokenization libraries (e.g., SentencePiece, tiktoken) to maximize control. In practice, that created a costly failure mode: silent training–serving skew. Our inference stack (vLLM) defaults to Hugging Face AutoTokenizer, and tiny differences in normalization, special token handling, or chat templating can yield different token boundaries — exactly the kind of mismatch that shows up later as inexplicable quality regressions. We fixed this by making Hugging Face AutoTokenizer the single source of truth. We then built a thin compatibility layer (BaseHFModelTokenizer) to handle post-training needs — setting padding tokens, injecting generation markers to support loss masking, and managing special tokens / semantic IDs — while ensuring the byte-level tokenization path matches production.
We do take a different approach for model implementations. Rather than training directly on transformers model classes, we maintain our own optimized, unified model definitions that can still load/save Hugging Face checkpoints. This layer is what enables framework-level optimizations — e.g., FlexAttention, memory-efficient chunked cross-entropy, consistent MFU accounting, and uniform LoRA extensibility — without re-implementing them separately for every model family. A unified module naming convention also makes it feasible to programmatically locate and swap components (Attention, MLP, output heads) across architectures, and provides a consistent surface for Tensor Parallelism and FSDP wrapping policies.
The trade-off is clear: supporting a new model family requires building a bridge between the Hugging Face reference implementation and our internal definition. To reduce that overhead, we use AI coding agents to automate much of the conversion work, with a strict logit verifier as the gate: given random inputs, our internal model must match the Hugging Face logits within tolerance. Because the acceptance criterion is mechanically checkable, agents can iterate autonomously until the implementation is correct, dramatically shortening the time-to-support for new architectures.
Today, this design means we can only train architectures we explicitly support — an intentional constraint shared by other high-performance systems like vLLM, SGLang, and torchtitan. To broaden coverage, we plan to add a fallback Hugging Face backend, similar to the compatibility patterns these projects use: users will be able to run training directly on native transformers models for rapid exploration of novel architectures, with the understanding that some framework optimizations and features may not apply in that mode.
Providing Differential Value
A post-training framework is only worth owning if it delivers clear value beyond assembling OSS components. We build on open source for velocity, but we invest heavily where off-the-shelf tools tend to be weakest: performance tuned to our workload characteristics, and integration with Netflix-specific model and business requirements. Here are some concrete examples:
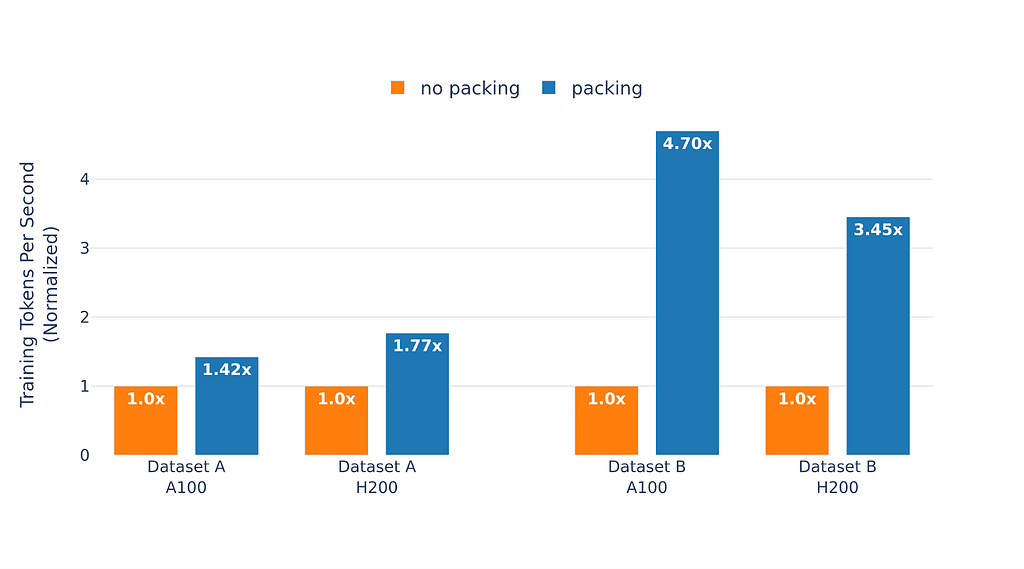
First, we optimize training efficiency for our real use cases. A representative example is extreme variance in sequence length. In FSDP-style training, long-tail sequences create stragglers: faster workers end up waiting at synchronization points for the slowest batch, lowering utilization. Standard bin-packing approaches help, but doing them offline at our data scale can add substantial preprocessing latency and make it harder to keep datasets fresh. Instead, we built on-the-fly sequence packing that streams samples from storage and dynamically packs them in memory. Packing runs asynchronously, overlapping CPU work with GPU compute. Figure 5 shows the impact: for our most skewed dataset, on-the-fly packing improved the effective token throughput by up to 4.7x.
We also encountered subtler performance cliffs around vocabulary expansion. Our workloads frequently add custom tokens and semantic IDs. We found that certain vocabulary sizes could cause the language model head to fall back from a highly optimized cuBLAS kernel to a much slower CUTLASS path, tripling that layer’s execution time. The framework now automatically pads vocabulary sizes to multiples of 64 so the compiler selects the fast kernel, preserving throughput without requiring developers to know these low-level constraints.
Second, owning the framework lets us support “non-standard” transformer use cases that generic LLM tooling rarely targets. For example, some internal models are trained on member interaction event sequences rather than natural language, and may require bespoke RL loops that integrate with highly-customized inference engines and optimize business-defined metrics. These workflows demand custom environments, reward computation, and orchestration patterns — while still needing the same underlying guarantees around performance, tracking, and fault tolerance. The framework is built to accommodate these specialized requirements without fragmenting into one-off pipelines, enabling rapid iteration.
Wrap up
Building the Netflix Post-Training Framework has been a continual exercise in balancing standardization with specialization. By staying anchored to the open-source ecosystem, we’ve avoided drifting into a proprietary stack that diverges from where the community is moving. At the same time, by owning the core abstractions around Data, Model, Compute, and Workflow, we’ve preserved the freedom to optimize for Netflix-scale training and Netflix-specific requirements.
In the process, we’ve moved post-training from a loose collection of scripts into a managed, scalable system. Whether the goal is maximizing SFT throughput, orchestrating multi-stage on-policy RL, or training transformers over member interaction sequences, the framework provides a consistent set of primitives to do so reliably and efficiently. As the field shifts toward more agentic, reasoning-heavy, and multimodal architectures, this foundation will help us translate new ideas into scalable GenAI prototypes — so experimentation is constrained by our imagination, not by operational complexity.
Acknowledgements
This work builds on the momentum of the broader open-source ML community. We’re especially grateful to the teams and contributors behind Torchtune, Torchtitan, and Verl, whose reference implementations and design patterns informed many of our training framework choices — particularly around scalable training recipes, distributed execution, and RL-oriented orchestration. We also thank our partner teams in Netflix AI for Member Systems for close collaboration, feedback, and shared problem-solving throughout the development and rollout of the Post-Training Framework, and the Training Platform team for providing the robust infrastructure and operational foundation that makes large-scale post-training possible.

Scaling LLM Post-Training at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Shedding old code with ecdysis: graceful restarts for Rust services at Cloudflare
Post Syndicated from Manuel Olguín Muñoz original https://blog.cloudflare.com/ecdysis-rust-graceful-restarts/
ecdysis | ˈekdəsəs |
noun
the process of shedding the old skin (in reptiles) or casting off the outer
cuticle (in insects and other arthropods).
How do you upgrade a network service, handling millions of requests per second around the globe, without disrupting even a single connection?
One of our solutions at Cloudflare to this massive challenge has long been ecdysis, a Rust library that implements graceful process restarts where no live connections are dropped, and no new connections are refused.
Last month, we open-sourced ecdysis, so now anyone can use it. After five years of production use at Cloudflare, ecdysis has proven itself by enabling zero-downtime upgrades across our critical Rust infrastructure, saving millions of requests with every restart across Cloudflare’s global network.
It’s hard to overstate the importance of getting these upgrades right, especially at the scale of Cloudflare’s network. Many of our services perform critical tasks such as traffic routing, TLS lifecycle management, or firewall rules enforcement, and must operate continuously. If one of these services goes down, even for an instant, the cascading impact can be catastrophic. Dropped connections and failed requests quickly lead to degraded customer performance and business impact.
When these services need updates, security patches can’t wait. Bug fixes need deployment and new features must roll out.
The naive approach involves waiting for the old process to be stopped before spinning up the new one, but this creates a window of time where connections are refused and requests are dropped. For a service handling thousands of requests per second in a single location, multiply that across hundreds of data centers, and a brief restart becomes millions of failed requests globally.
Let’s dig into the problem, and how ecdysis has been the solution for us — and maybe will be for you.
Links: GitHub | crates.io | docs.rs
The naive approach to restarting a service, as we mentioned, is to stop the old process and start a new one. This works acceptably for simple services that don’t handle real-time requests, but for network services processing live connections, this approach has critical limitations.
First, the naive approach creates a window during which no process is listening for incoming connections. When the old process stops, it closes its listening sockets, which causes the OS to immediately refuse new connections with ECONNREFUSED. Even if the new process starts immediately, there will always be a gap where nothing is accepting connections, whether milliseconds or seconds. For a service handling thousands of requests per second, even a gap of 100ms means hundreds of dropped connections.
Second, stopping the old process kills all already-established connections. A client uploading a large file or streaming video gets abruptly disconnected. Long-lived connections like WebSockets or gRPC streams are terminated mid-operation. From the client’s perspective, the service simply vanishes.
Binding the new process before shutting down the old one appears to solve this, but also introduces additional issues. The kernel normally allows only one process to bind to an address:port combination, but the SO_REUSEPORT socket option permits multiple binds. However, this creates a problem during process transitions that makes it unsuitable for graceful restarts.
When SO_REUSEPORT is used, the kernel creates separate listening sockets for each process and load balances new connections across these sockets. When the initial SYN packet for a connection is received, the kernel will assign it to one of the listening processes. Once the initial handshake is completed, the connection then sits in the accept() queue of the process until the process accepts it. If the process then exits before accepting this connection, it becomes orphaned and is terminated by the kernel. GitHub’s engineering team documented this issue extensively when building their GLB Director load balancer.
When we set out to design and build ecdysis, we identified four key goals for the library:
-
Old code can be completely shut down post-upgrade.
-
The new process has a grace period for initialization.
-
New code crashing during initialization is acceptable and shouldn’t affect the running service.
-
Only a single upgrade runs in parallel to avoid cascading failures.
ecdysis satisfies these requirements following an approach pioneered by NGINX, which has supported graceful upgrades since its early days. The approach is straightforward:
-
The parent process
fork()s a new child process. -
The child process replaces itself with a new version of the code with
execve(). -
The child process inherits the socket file descriptors via a named pipe shared with the parent.
-
The parent process waits for the child process to signal readiness before shutting down.

Crucially, the socket remains open throughout the transition. The child process inherits the listening socket from the parent as a file descriptor shared via a named pipe. During the child’s initialization, both processes share the same underlying kernel data structure, allowing the parent to continue accepting and processing new and existing connections. Once the child completes initialization, it notifies the parent and begins accepting connections. Upon receiving this ready notification, the parent immediately closes its copy of the listening socket and continues handling only existing connections.
This process eliminates coverage gaps while providing the child a safe initialization window. There is a brief window of time when both the parent and child may accept connections concurrently. This is intentional; any connections accepted by the parent are simply handled until completion as part of the draining process.
This model also provides the required crash safety. If the child process fails during initialization (e.g., due to a configuration error), it simply exits. Since the parent never stopped listening, no connections are dropped, and the upgrade can be retried once the problem is fixed.
ecdysis implements the forking model with first-class support for asynchronous programming through Tokio and systemd integration:
-
Tokio integration: Native async stream wrappers for Tokio. Inherited sockets become listeners without additional glue code. For synchronous services, ecdysis supports operation without async runtime requirements.
-
systemd-notify support: When the
systemd_notifyfeature is enabled, ecdysis automatically integrates with systemd’s process lifecycle notifications. SettingType=notify-reloadin your service unit file allows systemd to track upgrades correctly. -
systemd named sockets: The
systemd_socketsfeature enables ecdysis to manage systemd-activated sockets. Your service can be socket-activated and support graceful restarts simultaneously.
Platform note: ecdysis relies on Unix-specific syscalls for socket inheritance and process management. It does not work on Windows. This is a fundamental limitation of the forking approach.
Graceful restarts introduce security considerations. The forking model creates a brief window where two process generations coexist, both with access to the same listening sockets and potentially sensitive file descriptors.
ecdysis addresses these concerns through its design:
Fork-then-exec: ecdysis follows the traditional Unix pattern of fork() followed immediately by execve(). This ensures the child process starts with a clean slate: new address space, fresh code, and no inherited memory. Only explicitly-passed file descriptors cross the boundary.
Explicit inheritance: Only listening sockets and communication pipes are inherited. Other file descriptors are closed via CLOEXEC flags. This prevents accidental leakage of sensitive handles.
seccomp compatibility: Services using seccomp filters must allow fork() and execve(). This is a tradeoff: graceful restarts require these syscalls, so they cannot be blocked.
For most network services, these tradeoffs are acceptable. The security of the fork-exec model is well understood and has been battle-tested for decades in software like NGINX and Apache.
Let’s look at a practical example. Here’s a simplified TCP echo server that supports graceful restarts:
use ecdysis::tokio_ecdysis::{SignalKind, StopOnShutdown, TokioEcdysisBuilder};
use tokio::{net::TcpStream, task::JoinSet};
use futures::StreamExt;
use std::net::SocketAddr;

#[tokio::main]
async fn main() {
    // Create the ecdysis builder
    let mut ecdysis_builder = TokioEcdysisBuilder::new(
        SignalKind::hangup()  // Trigger upgrade/reload on SIGHUP
    ).unwrap();

    // Trigger stop on SIGUSR1
    ecdysis_builder
        .stop_on_signal(SignalKind::user_defined1())
        .unwrap();

    // Create listening socket - will be inherited by children
    let addr: SocketAddr = "0.0.0.0:8080".parse().unwrap();
    let stream = ecdysis_builder
        .build_listen_tcp(StopOnShutdown::Yes, addr, |builder, addr| {
            builder.set_reuse_address(true)?;
            builder.bind(&addr.into())?;
            builder.listen(128)?;
            Ok(builder.into())
        })
        .unwrap();

    // Spawn task to handle connections
    let server_handle = tokio::spawn(async move {
        let mut stream = stream;
        let mut set = JoinSet::new();
        while let Some(Ok(socket)) = stream.next().await {
            set.spawn(handle_connection(socket));
        }
        set.join_all().await;
    });

    // Signal readiness and wait for shutdown
    let (_ecdysis, shutdown_fut) = ecdysis_builder.ready().unwrap();
    let shutdown_reason = shutdown_fut.await;

    log::info!("Shutting down: {:?}", shutdown_reason);

    // Gracefully drain connections
    server_handle.await.unwrap();
}

async fn handle_connection(mut socket: TcpStream) {
    // Echo connection logic here
}
The key points:
-
build_listen_tcpcreates a listener that will be inherited by child processes. -
ready()signals to the parent process that initialization is complete and that it can safely exit. -
shutdown_fut.awaitblocks until an upgrade or stop is requested. This future only yields once the process should be shut down, either because an upgrade/reload was executed successfully or because a shutdown signal was received.
When you send SIGHUP to this process, here’s what ecdysis does…
…on the parent process:
-
Forks and execs a new instance of your binary.
-
Passes the listening socket to the child.
-
Waits for the child to call
ready(). -
Drains existing connections, then exits.
…on the child process:
-
Initializes itself following the same execution flow as the parent, except any sockets owned by ecdysis are inherited and not bound by the child.
-
Signals readiness to the parent by calling
ready(). -
Blocks waiting for a shutdown or upgrade signal.
ecdysis has been running in production at Cloudflare since 2021. It powers critical Rust infrastructure services deployed across 330+ data centers in 120+ countries. These services handle billions of requests per day and require frequent updates for security patches, feature releases, and configuration changes.
Every restart using ecdysis saves hundreds of thousands of requests that would otherwise be dropped during a naive stop/start cycle. Across our global footprint, this translates to millions of preserved connections and improved reliability for customers.
Graceful restart libraries exist for several ecosystems. Understanding when to use ecdysis versus alternatives is critical to choosing the right tool.
tableflip is our Go library that inspired ecdysis. It implements the same fork-and-inherit model for Go services. If you need Go, tableflip is a great option!
shellflip is Cloudflare’s other Rust graceful restart library, designed specifically for Oxy, our Rust-based proxy. shellflip is more opinionated: it assumes systemd and Tokio, and focuses on transferring arbitrary application state between parent and child. This makes it excellent for complex stateful services, or services that want to apply such aggressive sandboxing that they can’t even open their own sockets, but adds overhead for simpler cases.
ecdysis brings five years of production-hardened graceful restart capabilities to the Rust ecosystem. It’s the same technology protecting millions of connections across Cloudflare’s global network, now open-sourced and available for anyone!
Full documentation is available at docs.rs/ecdysis, including API reference, examples for common use cases, and steps for integrating with systemd.
The examples directory in the repository contains working code demonstrating TCP listeners, Unix socket listeners, and systemd integration.
The library is actively maintained by the Argo Smart Routing & Orpheus team, with contributions from teams across Cloudflare. We welcome contributions, bug reports, and feature requests on GitHub.
Whether you’re building a high-performance proxy, a long-lived API server, or any network service where uptime matters, ecdysis can provide a foundation for zero-downtime operations.
Start building: github.com/cloudflare/ecdysis
LWT Season 13 x The Pitt
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/9BDUG0FeRPw
Comic for 2026.02.13 – New Invention
Post Syndicated from Explosm.net original https://explosm.net/comics/new-invention
New Cyanide and Happiness Comic
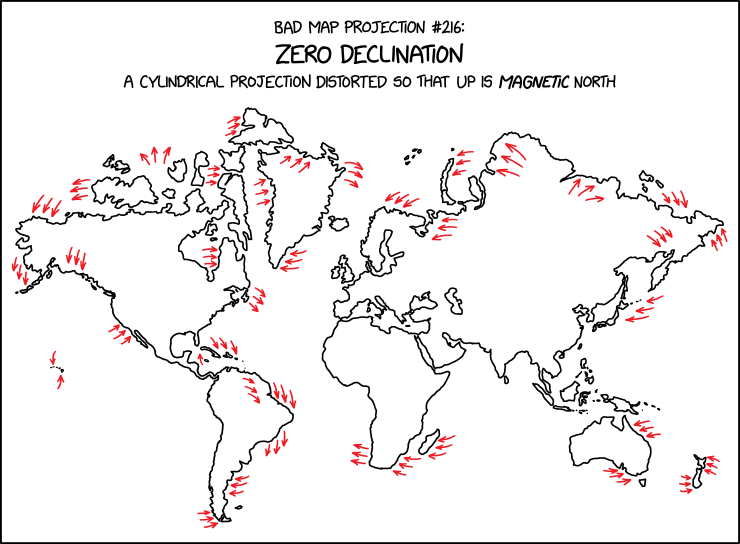
Bad Map Projection: Zero Declination
Post Syndicated from xkcd.com original https://xkcd.com/3207/
Matching your Ingestion Strategy with your OpenSearch Query Patterns
Post Syndicated from Rakan Kandah original https://aws.amazon.com/blogs/big-data/matching-your-ingestion-strategy-with-your-opensearch-query-patterns/
Choosing the right indexing strategy for your Amazon OpenSearch Service clusters helps deliver low-latency, accurate results while maintaining efficiency. If your access patterns require complex queries, it’s best to re-evaluate your indexing strategy.
In this post, we demonstrate how you can create a custom index analyzer in OpenSearch to implement autocomplete functionality efficiently by using the Edge n-gram tokenizer to match prefix queries without using wildcards.
What is an index analyzer?
Index analyzers are used to analyze text fields during ingestion of a document. The analyzer outputs the terms you can use to match queries
By default, OpenSearch indexes your data using the standard index analyzer. The standard index analyzer splits tokens on spaces, converts tokens to lowercase, and removes most punctuation. For some use cases (like log analytics), the standard index analyzer might be all you need.
Standard Index Analyzer
Let’s look at what the standard index analyzer does. We’ll use the _analyze API to test how the standard index analyzer tokenizes the sentence “Standard Index Analyzer.”
Note: You can run all the commands in this post using OpenSearch DevTools in the OpenSearch Dashboard.
Notice how each word was lowercased and the period (punctuation) was removed.
Creating your own index analyzer
OpenSearch offers a large number of built in analyzers that you can use for different access patterns. It also lets you build your own custom analyzer, configured for your specific search needs. In the following example, we are going to configure a custom analyzer that returns partial word matches for a list of addresses. The analyzer is specifically designed for autocomplete functionality, enabling end users to quickly find addresses without having to type out (or remember) an entire address. Autocomplete allows OpenSearch to effectively complete the search term based off matched prefixes.
First, create an index called standard_index_test:
Specifying the analyzer as standard is not required because the standard analyzer is the default analyzer.
To test, bulk add some data to our standard_index_test that we created.
Query this data using the text “ope”.
When searching for the term “ope”, we don’t get any matches. To see why, we can dive a little deeper into the standard index analyzer and see how our text is being tokenized. Test the standard index analyzer with the address “456 OpenSearch Drive Anytown, Ny 78910”.
The standard index analyzer has tokenized the address into individual terms: 456, opensearch, drive and so on. That means, unless you search for an individual token (like 456 or opensearch) o, op, ope , and even open won’t yield any results. One option is to use wildcards while still using the standard index analyzer for indexing:
The wildcard query would match “456 OpenSearch Drive Anytown, Ny 78910” but wildcard queries can be resource intensive and slow. Querying for ope* in OpenSearch results in iterating over each term in the index, bypassing optimizations of inverted index lookups. This results in higher memory usage and slower performance. To improve the performance of our query execution and search experience, we can use an index analyzer that better suits our access patterns.
Edge n-gram
The Edge n-gram tokenizer helps you find partial matches and avoids the use of wildcards by tokenizing prefixes of a single word. For example, the input word coffee is expanded into all its prefixes, c, co , cof, and so on. It can limit the prefixes to those between a minimum (min_gram) and maximum (max_gram) length. So with min_gram=3 and max_gram=5, it will expand “coffee” to cof, coff, and coffe.
Create a new index called custom_index with our own custom index analyzer that uses Edge n-grams. Set the minimum token length (min_gram) to 3 characters, and the maximum token length (max_gram) to 20 characters. The min_gram and max_gram sets the minimum and maximum returned token length respectively. You should select the min_gram and max_gram based off your access patterns. In this example, we’re searching for the term “ope” so we don’t need to set the minimum length to anything less than 3 since we’re not searching for terms like o or op. Setting the min_gram too low can lead to high latency. Likewise, we don’t need to set the maximum length to anything greater than 20 as no individual token will exceed the length of 20. Setting the maximum length to 20 gives us room to spare in case we do eventually ingest an address with a longer token length. Note, the index we are creating here is specifically for autocomplete functionality and is likely unnecessary for a general search index.
In the above code, we created an index called custom_index with a custom analyzer named autocomplete. The analyzer performs the following:
- It uses the standard tokenizer to split text into tokens
- A lowercase filter is applied to lowercase all the tokens
- The tokens are then further broken into smaller chunks based off the minimum and maximum values of the edge_ngram
The search analyzer is configured to use the standard analyzer to reduce query processing required at search time. We have already applied our custom analyzer to split the text for us upon ingestion, and we do not need to repeat this process when searching. Test how the custom analyzer analyzes the text Lexington Avenue:
Notice how the tokens are lowercase and now support partial matches. Now that we’ve seen how our analyzer tokenizes our text, bulk add some data:
And test!
You have configured a custom n-gram analyzer to find partial words matches within our list of addresses.
Note, there is a tradeoff between using non-standard index analyzers and writing compute intensive queries. Analyzers can affect indexing throughput and increase the overall index size, especially if used inefficiently. For example, when creating the custom_index, the search analyzer was set to use the standard analyzer. Using n_grams for analysis upon ingestion and search would have impacted cluster performance unnecessarily. Additionally, we set the min_gram and max_gram to values that matched our access patterns, ensuring we didn’t create more n_grams than we needed to for our search use case. This allowed us to gain the benefits of optimizing search without impacting our ingestion throughput.
Conclusion
In this post, we changed how OpenSearch indexed our data to simplify and speed up autocomplete queries. In our case, using the Edge n-grams allowed OpenSearch to match parts of an address and yield precise results without compromising cluster performance with a wildcard query.
It’s always important to test your cluster before deploying in a production environment. Understanding your access patterns is essential to optimizing your cluster from both an indexing and searching perspective. Use the guidelines in this post as a starting point. Confirm your access patterns before creating an index, then begin experimenting with different index analyzers in a test environment to see how they can simplify your queries and improve overall cluster performance. For more reading on general OpenSearch cluster optimization techniques, refer to the Get started with Amazon OpenSearch Service: T-shirt-size your domain post.
About the authors
YuanLey AQC113-X1 10Gbase-T PCIe Network Card Review
Post Syndicated from Rohit Kumar original https://www.servethehome.com/yuanley-aqc113-x1-10gbase-t-marvell-pcie-network-card-review/
In our YuanLey AQC113-X1 10Gbase-T review, we see how this Marvell AQC113-based NIC performs and what it offers
The post YuanLey AQC113-X1 10Gbase-T PCIe Network Card Review appeared first on ServeTheHome.
[$] Poisoning scraperbots with iocaine
Post Syndicated from daroc original https://lwn.net/Articles/1056953/
Web sites are being increasingly beset by AI scraperbots — a problem that we have
written about before, and which has slowly
ramped up to an occasional de-facto DDoS attack. This has not gone
uncontested, however: web site operators from around the world have been working on
inventive countermeasures. These solutions target the problem posed by scraperbots in different ways;
iocaine, a MIT-licensed nonsense generator, is designed
to make scraped text less useful by poisoning it with fake data. The hope is to
make running scraperbots not economically viable, and thereby address the
problem at its root instead of playing an eternal game of Whac-A-Mole.
[$] The reverting of revocable
Post Syndicated from corbet original https://lwn.net/Articles/1058041/
Transient devices pose a special challenge for an operating-system kernel.
They can disappear at any time, leaving behind kernel data structures that
no longer refer to an existing device, but which may still be in use by
unknown kernel code. Managing the resulting lifecycle issues has
frustrated kernel developers for years. In September 2025, the revocable resource-management patch series
from Tzung-Bi Shih appeared to offer a partial solution to this problem.
Since then, though, other problems have arisen, and the planned merging of
this series into the 7.0 release has been called off.
Embodied machine learning: From research ideas to classroom activities
Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/embodied-machine-learning-from-research-ideas-to-classroom-activities/
Where do great research ideas come from in computer science education? We might think of research breakthroughs as a single moment of genius, but in reality impactful research is often the result of many years of iterative development. In November’s research seminar, we heard from Karl-Emil Kjær Bilstrup, a researcher at the University of Copenhagen, about his work to develop ML-Machine. This work uses embodied learning principles and the BBC micro:bit to introduce learners to machine learning concepts. Findings from this research have been used to develop the micro:bit CreateAI resources, and in this blog, we will explain the research journey from initial small-scale work to educational resources used by many young learners around the world.
From hypothetical ethics to concrete machines
In Karl-Emil’s first research study, students used prompt cards to develop ideas for machine learning applications that could solve real-world problems, and to discuss the ethical dilemmas associated with their solutions. Students found it difficult to address these ethical dilemmas in their designs; for example, their ideas often featured a trade-off of user privacy. The findings from this research informed Karl-Emil’s next study, which moved from hypothetical scenarios to implementing machine learning in real-world settings.
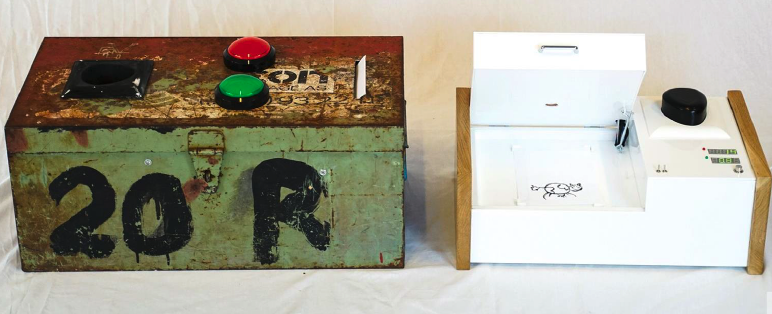
The ‘Machine Learning Machine’ study made machine learning processes tangible for students through the use of two physical boxes, shown in the picture below. Students created drawings and fed them into the first box to train a model, and then tested the model by placing new drawings under a camera in the second box and having the model produce predictions of what the drawings showed. For example, students could draw pictures of the sun to represent daytime and the moon to represent nighttime to train a model to predict whether new drawings represented day or night. The machine was built for slow interaction, giving students time to think about the concepts and practices that they were developing. In a follow-up study, a new version of the Machine Learning Machine had been designed, which was controlled using a graphical user interface (GUI). This allowed users to “unbox” and influence parts of the machine learning process. For example, students could adjust the number of complete passes (called ‘epochs’) through the training data to improve the model’s accuracy.
The two studies with the Machine Learning Machines provided many useful findings for teaching about machine learning with K–12 (primary and secondary) learners. However, two constraints remained: firstly, there were limited opportunities for whole-class work because there was only one Machine Learning Machine, and secondly, learning experiences needed to be better connected to examples from students’ daily lives. As a result, the next iteration in Karl-Emil’s research involved using the micro:bit, which ensured access to a tangible device for every student, and a new graphical platform called ML-Machine that students could interact with.
Machine learning and the micro:bit
The micro:bit is a small, programmable computing device that features sensors to gather data from the immediate environment. For example, the accelerometer is a motion sensor that can detect when the micro:bit is tilted from left to right, backwards and forwards, and up and down. Using the micro:bit with ML-Machine and some common household objects, students can create simple machine learning models that use data from the micro:bit’s accelerometer to detect whether the micro:bit is moving. This is a very different approach from rule-based programs on the micro:bit, where students might use programming constructs such as if statements to detect movement if the numerical reading from the accelerometer is above a certain value. Here, a machine learning model trained using a set of 20 examples is used to analyse live data readings and produce predictions about whether the micro:bit is moving.
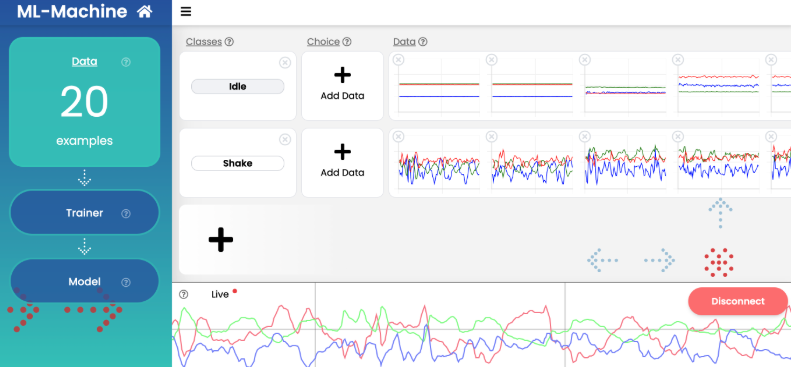
In our seminar, Karl-Emil gave a live demonstration of the ML-Machine toolkit, so we highly recommend watching the recording to see how this toolkit brings machine learning concepts to life.
ML-Machine is the precursor to the micro:bit CreateAI resources, and the software is fully open-source. However, the innovation doesn’t stop there: Karl-Emil also explained that he is currently developing a new tool called math.ml-machine.org, where students can train a neural network and see a visualised k-nearest neighbour model to explore how a model makes predictions. The research journey is continuing, with new possibilities for educational opportunities to teach about machine learning.
Embodied learning
The idea of embodied learning is interwoven throughout all of Karl-Emil’s research projects and is a cornerstone of all of his work. Embodied learning suggests that we learn more effectively when our whole body is involved in the learning process, not just our minds. For example, in the work described in this seminar, the Machine Learning Machines and the micro:bit were all tangible devices that students could touch and see.
Embodied learning is particularly important in activities that involve working with data-driven systems. In traditional programming activities, the flow of code can be traced transparently through a program. However, machine learning models are more opaque, and their outputs cannot be traced step by step. Students can benefit from using bodily movements and sensorimotor information to help understand machine learning concepts.
The ML-Machine toolkit was designed to support students to learn through embodied learning in three different ways:
- Enacting machine learning processes: Students used bodily movement to collect the data samples needed for the ML-Machine model to detect and predict gestures
- Using machine learning as a design material: Students created concrete ‘objects-to-think-with’, which helps form deeper connections to abstract concepts
- Embodied exploration of machine learning: Students experienced how their bodily movements were translated into data points on the screen
Embodied learning helped students grasp concepts such as data quality. They could see how their bodily movements were being translated into digital data, and could spot when movements that appeared different to them were being classified as similar by the ML-Machine model. One case study participant described that the immediate feedback on screen made the concept of machine learning feel as if it were “coming to life as they [the students] manipulate something themselves and they’ve got control over it”.
Find out more
Karl-Emil’s work shows how research ideas can be used in the classroom through a cycle of discovery, design, and reflection. From prompt cards exploring ethics to tangible machines and the micro:bit-based ML-Machine, his research shows how embodied learning can make complex ideas like machine learning not only understandable, but deeply engaging for young learners. The micro:bit CreateAI resources are a great example of how research findings can evolve into accessible, hands-on tools that empower educators and students alike. As this work continues to grow, it invites us to imagine new ways for learners to experience machine learning not as abstract theory, but as something they can see, feel, and shape with their own hands.
If you’d like to try out some of the ideas from this seminar, here are some useful resources:
- Explore machine learning projects using the micro:bit: micro:bit CreateAI and our Dance detector project are great places to start
- Find out more about the research: Read more about Karl-Emil’s work in this open-access paper
- Investigate new tools: Explore neural networks and k-nearest neighbours algorithms in the new maths-focused version of ML-Machine at math.ml-machine.org
Join our next seminar
Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!
To sign up and take part in our research seminars, click below:
You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.
The post Embodied machine learning: From research ideas to classroom activities appeared first on Raspberry Pi Foundation.