Post Syndicated from The Atlantic original https://www.youtube.com/shorts/0RI3Hfvfb8g
[$] Lessons from creating a gaming-oriented scheduler
Post Syndicated from jake original https://lwn.net/Articles/1051430/
At the 2025 Linux Plumbers
Conference (LPC), held in Tokyo in mid-December, Changwoo Min led a session on what
he has learned while developing the
“latency-criticality
aware virtual deadline” (LAVD) scheduler, which is aimed at gaming
workloads. The session was part of the Gaming
on Linux microconference, which is a new entrant into LPC; organizers
hope to see it return next year in
Prague and, presumably, beyond. LAVD uses the extensible scheduler class (sched_ext) and has
the primary goal of minimizing stuttering
in games;
it is implemented in a combination of BPF and Rust.
[$] 2025 Linux and free software timeline
Post Syndicated from jzb original https://lwn.net/Articles/1051808/
Last year we
revived the tradition of publishing a timeline of
notable events from the previous year. Since that seemed to go over
well, we decided we should continue the practice and look back on some
of the most noteworthy events and releases of 2025.
Why Matter Finally Makes Sense (and Wi-Fi Doesn’t)
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=XIjsPqn8Vxg
Why Trump’s Foreign Policy Is Such a Clown Show | The David Frum Show
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=UE7L-sNFNkE
IPFire 2.29 Core Update 199 released
Post Syndicated from jzb original https://lwn.net/Articles/1053083/
The IPFire project, an
open-source firewall Linux distribution, has released version
2.29 – Core Update 199. Notable changes in this release include an
update to Linux 6.12.58, support for WiFi 6 and 7 features on
wireless access points, as well as native support for link-local
discovery protocol (LLDP) and Cisco discovery protocol (CDP).
Когато грешната прогноза е добра новина
Post Syndicated from Светла Енчева original https://www.toest.bg/kogato-greshnata-prognoza-e-dobra-novina/

Нова година – нови избори. И да не сте чели „Пътеводител на галактическия стопаджия“, е много вероятно да сте чували за особеното значение на числото 42. В поредицата на Дъглас Адамс 42 е „Отговорът на Вечния Въпрос за Живота, Вселената и Всичко останало“. Ала след като имаме отговора, още по-трудната задача е да разберем какъв, джанъм, е въпросът. Понякога и с електоралното поведение е така – избирателите искат нещо, борят се за него, протестират и чак след като го получат, се вижда, че то не решава проблемите им. А може дори да създаде нови.
Тези статии не остаряха добре
Политолозите обясняват постфактум защо прогнозите им не са се сбъднали, припомня шеговитото клише Александър Драганов. А Ан Фам, главната редакторка на „Тоест“, обича да казва, че иска в сайта да има статии, които „остаряват добре“. Без да съм учила политология, след няколко протеста в рамките на по-малко от месец вече имам куп статии, които не остаряха добре. Но това не е непременно лоша новина.
Точно година преди най-големия протест от 1990 г. насам се подписах под заглавието „Защо в България вече няма масови протести?“. Е, очевидно вече има. И то толкова масови, че само три от тях, проведени в разстояние на две седмици (между 26 ноември и 10 декември 2025 г.), бяха достатъчни, за да падне правителството. На всичко отгоре площадите продължиха да се пълнят и след оставката. За сравнение, започналите през 2023 г. протести срещу правителството на Пламен Орешарски, предложило Делян Пеевски за шеф на ДАНС,
продължиха повече от година.
По време на хиперинфлацията през 1997 г. протести имаше на практика всекидневно от 10 януари до 4 февруари, когато Николай Добрев от БСП върна на новоизбрания президент Петър Стоянов мандата за съставяне на правителство.
След щурмуването на „Росенец“ през 2020 г. писах за враждебната към етническите малцинства реторика на демократични политици и протестиращи граждани. Опитвах се да обясня, че не можем да очакваме българските мюсюлмани и роми да пожелаят да гласуват за хора, които демонстрират презрение към тях. И за листи, в които на практика не са представени. Сред активно протестиращите в края на 2025 г. обаче дойдоха и етнически турци, и роми. Някои от тях говориха и от трибуните.
В средата на 2024 г. упрекнах идентифициращите се като демократични партии, че не полагат адекватни усилия да печелят демократични избиратели. Че посланията им са неразбираеми и високомерни, че не си дават сметка за различните групи хора със специфични характеристики, ценности и интереси. И ги посъветвах какво да направят, за да имат посланията им чуваемост. Не ми се вярва отговорните за комуникацията в демократичните партии да са чели препоръките ми, и ми е трудно да се отърся от шока, че те (особено „Продължаваме промяната“)
рязко станаха комуникационно адекватни.
Посланията им резонираха и извън София. Напълниха се площадите и на градове, където не сме чували за протести до този момент. Включиха се много млади хора.
Специално внимание заслужава протестната музика. Наивно-идеалистичните и отдавна изхабени песни от началото на 90-те и възрожденско-патриотичният попфолк, допринесъл за политическия възход на Слави Трифонов, останаха в миналото. По площадите се чува звучащата на протести на различни места по света песен от антиутопичната поредица „Игрите на глада“. По-важното е, че протестът за отрицателно време произведе собствена попкултура, включително музика, преобладаващо пънк. А изпълнението на живо с участието на Асен Василев на парчето на варненската група PIZZZA с цитати от заседанието, на което председателят на ПП Асен Василев изрече култовата реплика „Кой разпореди това безобразие?“, стана вайръл. Както впрочем и самият Асен Василев.
Разбира се, причината за масовите протести няма как да е само в успешната политическа комуникация. Кражбите на публични средства стават все по-видими. Проектобюджетът, който беше поводът за общественото недоволство, на практика ги официализираше. И все пак организаторите на протестите можеха да реагират на общественото недоволство и по недотам адекватен начин, както неведнъж се е случвало, и в резултат по-малко хора да излязат по площадите.
На хубаво ли е много хубавото?
Еуфорията от мащаба и успеха на протестите лесно може да прелее във вярата в изборната победа на коалицията, която ги организира – ПП–ДБ. Бившата правосъдна министърка от „Да, България“ Надежда Йорданова дори даде заявка, че коалицията ще се бори не просто за победа на изборите, а за мнозинство.
Големият въпрос обаче е каква електорална форма ще приеме натрупаната мобилизация.
Няма гаранция, че подкрепящите протестите ще дадат гласа си точно за ПП–ДБ. Нещо повече – при такава обществена енергия е логично да възникнат нови политически субекти. Че има поле за такива, се вижда и от изследванията на общественото мнение. По данни на „Алфа Рисърч“ от декември например цели 40% от гласоподавателите са в очакване да се появи нещо ново на политическия хоризонт. Близо 10% от заявилите, че ще гласуват, не искат да пуснат бюлетина за никоя от парламентарно представените партии, а други 13,3% още не са решили.
Засега тактиката е максимално разширяване на периферията чрез включване на хора с най-различни профили и възгледи, обединени от недоволството си от кражбите и от тандема Пеевски – Борисов. Другата сериозна тема обаче – за геополитическата ориентация на България – остава по-скоро в скоби. Тя е приоритет на ПП–ДБ, но далеч не на всички, подкрепящи протестите.
Партиите в ПП–ДБ обаче са комай единствените еднозначно проевропейски политически субекти в парламента с шансове да влязат и в следващия.
Правителството на Росен Желязков, което протестите свалиха от власт, се води проевропейско и именно по негово време България беше окончателно приета в еврозоната. ГЕРБ обаче е по-скоро фасадно (и в името на фондовете за усвояване) проевропейска партия. През годините Бойко Борисов нееднократно е изразявал симпатии и към Владимир Путин, и към евроскептични политици като Виктор Орбан.
Що се отнася до „Ново начало“, Пеевски няма ясна политическа идеология, още по-малко демократична. ДПС дълги години беше част от групата на либералите в Европарламента. Но след като тя и европейската либерална партия АЛДЕ препоръчаха „Ново начало“ да бъде изключено от редиците им, депутатите от ДПС на Пеевски сами напуснаха.
В същото време не трябва да се подценяват страховете и недоволството около приемането на еврото, макар протестите против въвеждането му да не са толкова масови. Темата за корупцията лесно може да се свърже със страха от обедняването, икономическите проблеми да се припишат и на еврото и в резултат всички несгоди да се асоциират с ЕС. Готова рецепта за идване на евроскептици на бял кон.
Вече сме преживявали нещо подобно, макар че то не доведе до обрат в геополитическата ориентация на България.
Кои бяха големите печеливши от протестите през 2020 г., когато Христо Иванов и Иво Мирчев щурмуваха „Росенец“? В разгара им Румен Радев излезе герой и това подсигури втория му мандат на президентския пост. Другите големи печеливши бяха ИТН. И Радев, и ИТН не могат да се характеризират като проевропейски – президентът е по-скоро пропутински настроен, а партията на Слави Трифонов се заиграва с популисткия национализъм. Последва поредица от служебни правителства, чиито премиери упорито дърпаха към Русия.
Да, след протестите през 2020 г. изгря и звездата на Кирил Петков и Асен Василев, които по-късно основаха „Продължаваме промяната“. Само че партията им възникна като президентски проект. И електоралната ѝ подкрепа чувствително намаля, когато тя се разграничи от външнополитическия дневен ред на Радев.
Както беше казал Кирил Петков в разпространения от Радостин Василев запис от заседание на Националния съвет на ПП: „Ние изведнъж се почувствахме, че сме някакви гении“, а всъщност „цялата машина на Радев и цялата държава е работела за нас“.
Днес Румен Радев вече не си прави труда да се преструва, че няма да влиза в политиката, макар да се разграничи от новоучредената партия „Трети март“, която го обяви за свой „неформален лидер“.
Възможно ли е и настоящата обществена енергия да е насочвана в една или друга посока от някаква „машина“,
без организаторите на протестите да си дават сметка за нея? Да приемем това за даденост би било конспиративна теория, но да го отричаме напълно би било наивно. Колкото и да е неприятно да си го признаем, хората от службите и техните ученици умеят да въздействат много по-добре на общественото мнение от демократичните политици, които разчитат на убеждаване с разумни аргументи.
Да се надяваш да си в грешка
За изразените опасения има и външнополитически основания. Бившите социалистически страни в ЕС са подложени на силен натиск да се отклонят от европейската си и продемократична ориентация. Става дума за Унгария, Словакия, до неотдавна Полша (макар че там управлението не беше проруско, беше антидемократично), отскоро и Чехия. Дори западноевропейски държави като Италия или Австрия не са имунизирани от евроскептичния популизъм.
Не е за пренебрегване и управлението на Доналд Тръмп, за когото европейското единство е трън в очите. По време на втория си мандат като президент, при всичкия хаос, който натворява, той със систематично упорство предприема действия, в резултат на които международното право (а и правото изобщо) все повече заприличва на куха структура. Последният случай е смяната на властта във Венецуела с военна намеса – без санкция нито от ООН, нито дори от Конгреса на САЩ.
В тази ситуация кое ще помогне на България да устои? Дали имаме служби, способни да противостоят на чужди вмешателства в политиката ни, или работещи институции, които ще отстояват принципите на европейското право?
Не от всяка масова еуфория се раждат демократични плодове. Да си припомним и ентусиазма по време на т.нар. Арабска пролет – тя доведе на власт фундаменталистки режими.
Мислим си, че е трудно да детронираме Пеевски. Но ако на власт се установи антидемократично управление, свалянето му може да се окаже невъзможна задача. Днес можем да протестираме, но правото на протест не е даденост.
Дано и тази статия не остарее добре. За да не се сбъднат прогнозите в нея обаче, би било добре те да се имат предвид – като предупреждение.
AMD’s EPYC Venice, Instinct MI455X, & Helios Hardware On Display for First Time at CES 2026
Post Syndicated from Ryan Smith original https://www.servethehome.com/amds-epyc-venice-instinct-mi455x-helios-hardware-on-display-for-first-time-at-ces-2026/
Alongside AMD’s numerous client-focused hardware announcements during their CES 2026 keynote, the company also devoted a bit of attention to their data center/server products. Though the company is essentially mid-cycle on its major data center products right now – and thus is not launching anything in the immediate timeframe – AMD still opted to use […]
The post AMD’s EPYC Venice, Instinct MI455X, & Helios Hardware On Display for First Time at CES 2026 appeared first on ServeTheHome.
Google will now only release Android source code twice a year (Android Authority)
Post Syndicated from corbet original https://lwn.net/Articles/1053061/
Android Authority reports
that Google will be reducing the frequency of releases of code to the
Android Open Source Project to only twice per year.
A spokesperson for Google offered some additional context on this
decision, stating that it helps simplify development, eliminates
the complexity of managing multiple code branches, and allows them
to deliver more stable and secure code to Android platform
developers. The spokesperson also reiterated that Google’s
commitment to AOSP is unchanged and that this new release schedule
helps the company build a more robust and secure foundation for the
Android ecosystem.
The release schedule for security patches is unchanged.
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1053057/
Security updates have been issued by AlmaLinux (resource-agents, ruby:3.3, thunderbird, and xorg-x11-server), Fedora (libpcap), Red Hat (brotli), Slackware (libsodium), SUSE (dcmtk, govulncheck-vulndb, libpcap, mozjs60, qemu, rsync, and usbmuxd), and Ubuntu (glib2.0 and linux-raspi, linux-raspi-5.4).
Key Takeaways and Top Cybersecurity Predictions for 2026
Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/it-key-takeaways-top-cybersecurity-predictions-2026
As the threat landscape keeps shifting, security teams are being asked to do more than react. They are expected to look ahead, connect the dots, and make decisions in environments that change faster every year. That challenge was at the heart of Rapid7’s 2026 Security Predictions webinar, where our experts reflected on what the past year revealed about attacker behavior, defender priorities, and the realities of running a modern SOC.
The conversation looked back just long enough to spot the patterns that matter, then turned forward to the forces shaping 2026. Geopolitics, insider risk, and the need for context-driven defense all surfaced repeatedly. The takeaway was simple but important. Attackers are adapting quickly, and security teams need to adapt with the same urgency.
Below are the key takeaways from the discussion, along with the top predictions shaping the year ahead.
Key takeaways from the discussion
The threat landscape is no longer isolated
One of the strongest themes from the webinar was how interconnected today’s risks have become. Cyber activity does not exist in a vacuum. Geopolitical tensions, economic pressure, workforce challenges, and technological acceleration all feed directly into attacker behavior.
Security teams can no longer separate cyber risk from broader business and global risk. Decisions made outside the SOC, from supplier choices to workforce strategy, increasingly influence exposure and attack paths.
Identity and access remain the most reliable attack paths
Despite continued investment in perimeter defenses, attackers are still finding success through compromised credentials, misused access, and human error. The webinar panel reinforced that identity-based compromise remains one of the most consistent and scalable techniques used by threat actors.
This means defenders must treat identity, behavior, and access governance as core detection and response signals, not secondary controls.
Speed without context creates noise, not security
The rise of AI-driven attacks and automation has increased the volume and pace of activity security teams must process. However, the panel stressed that faster alerts alone do not improve outcomes.
Without understanding which assets matter, which exposures are exploitable, and which alerts represent real risk, teams risk moving quickly in the wrong direction. Context is now essential for effective prioritization and response.
The top cybersecurity predictions for 2026
1. Geopolitical fault lines will redraw the cyber battlefield
In 2026, geopolitical tensions will continue to spill into the digital domain, with private organizations increasingly caught in the middle. State-aligned and state-tolerated groups will target critical supply chains, service providers, and global enterprises as proxy targets, blending espionage with economic disruption.
For security teams, this means geopolitical risk must be factored into threat modeling, vendor assessments, and incident response planning. Even organizations far from traditional conflict zones may find themselves impacted by campaigns tied to global tensions.
2. Insider threats will dominate breach root causes
The panel highlighted that many of tomorrow’s breaches will not start with attackers breaking in, but with access already in place. Insider threats, driven by simple negligence, compromised credentials, or monetized access selling, will continue to rise.
Economic stress, workforce changes, and growing access complexity all contribute to this trend. As a result, organizations must focus more on access hygiene, behavior monitoring, and creating environments where employees can report mistakes early without fear.
3. Context will become the new currency of cyber performance
As attacks scale and exploitation windows shrink, the ability to understand what matters most will define successful security operations. The panel emphasized that visibility alone is no longer enough.
Security teams that integrate exposure management, detection, and response will outperform those relying on disconnected tools and alert-heavy workflows. Context-rich defense allows teams to triage faster, investigate smarter, and respond based on real business risk rather than alert volume.
What this means for security teams heading into 2026
The predictions shared during the webinar point to a future where success depends less on adding more tools and more on using intelligence, context, and automation effectively. Security teams that can unify visibility, prioritize risk, and act decisively will be better positioned to keep pace with increasingly adaptive attackers.
The message from the panel was clear. 2026 will reward teams that focus on understanding their environment, aligning security efforts with real-world risk, and preparing for threats shaped by forces far beyond the SOC.
Watch the 2026 Security Predictions webinar to hear directly from Rapid7’s experts on what’s shaping the threat landscape and how security teams should prepare.
The Turkish Abductions: Corsairs in Iceland
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=97CB0wW54Qo
The Wegman’s Supermarket Chain Is Probably Using Facial Recognition
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/01/the-wegmans-supermarket-chain-is-probably-using-facial-recognition.html
The New York City Wegman’s is collecting biometric information about customers.
What shaped computing education in 2025 — and what comes next
Post Syndicated from Liz Eaton original https://www.raspberrypi.org/blog/what-shaped-computing-education-in-2025-and-what-comes-next/
To mark the start of 2026, we’re releasing a special episode of our Hello World podcast, which reflects on the key developments in computing education during 2025 and considers the trends likely to shape the year ahead.
Hosted by James Robinson, the episode brings together a conversation between three Foundation team members — Rehana Al-Soltane, Dr Bobby Whyte, and Laura James — and perspectives from colleagues and partners in Kenya, South Africa, and Greece.
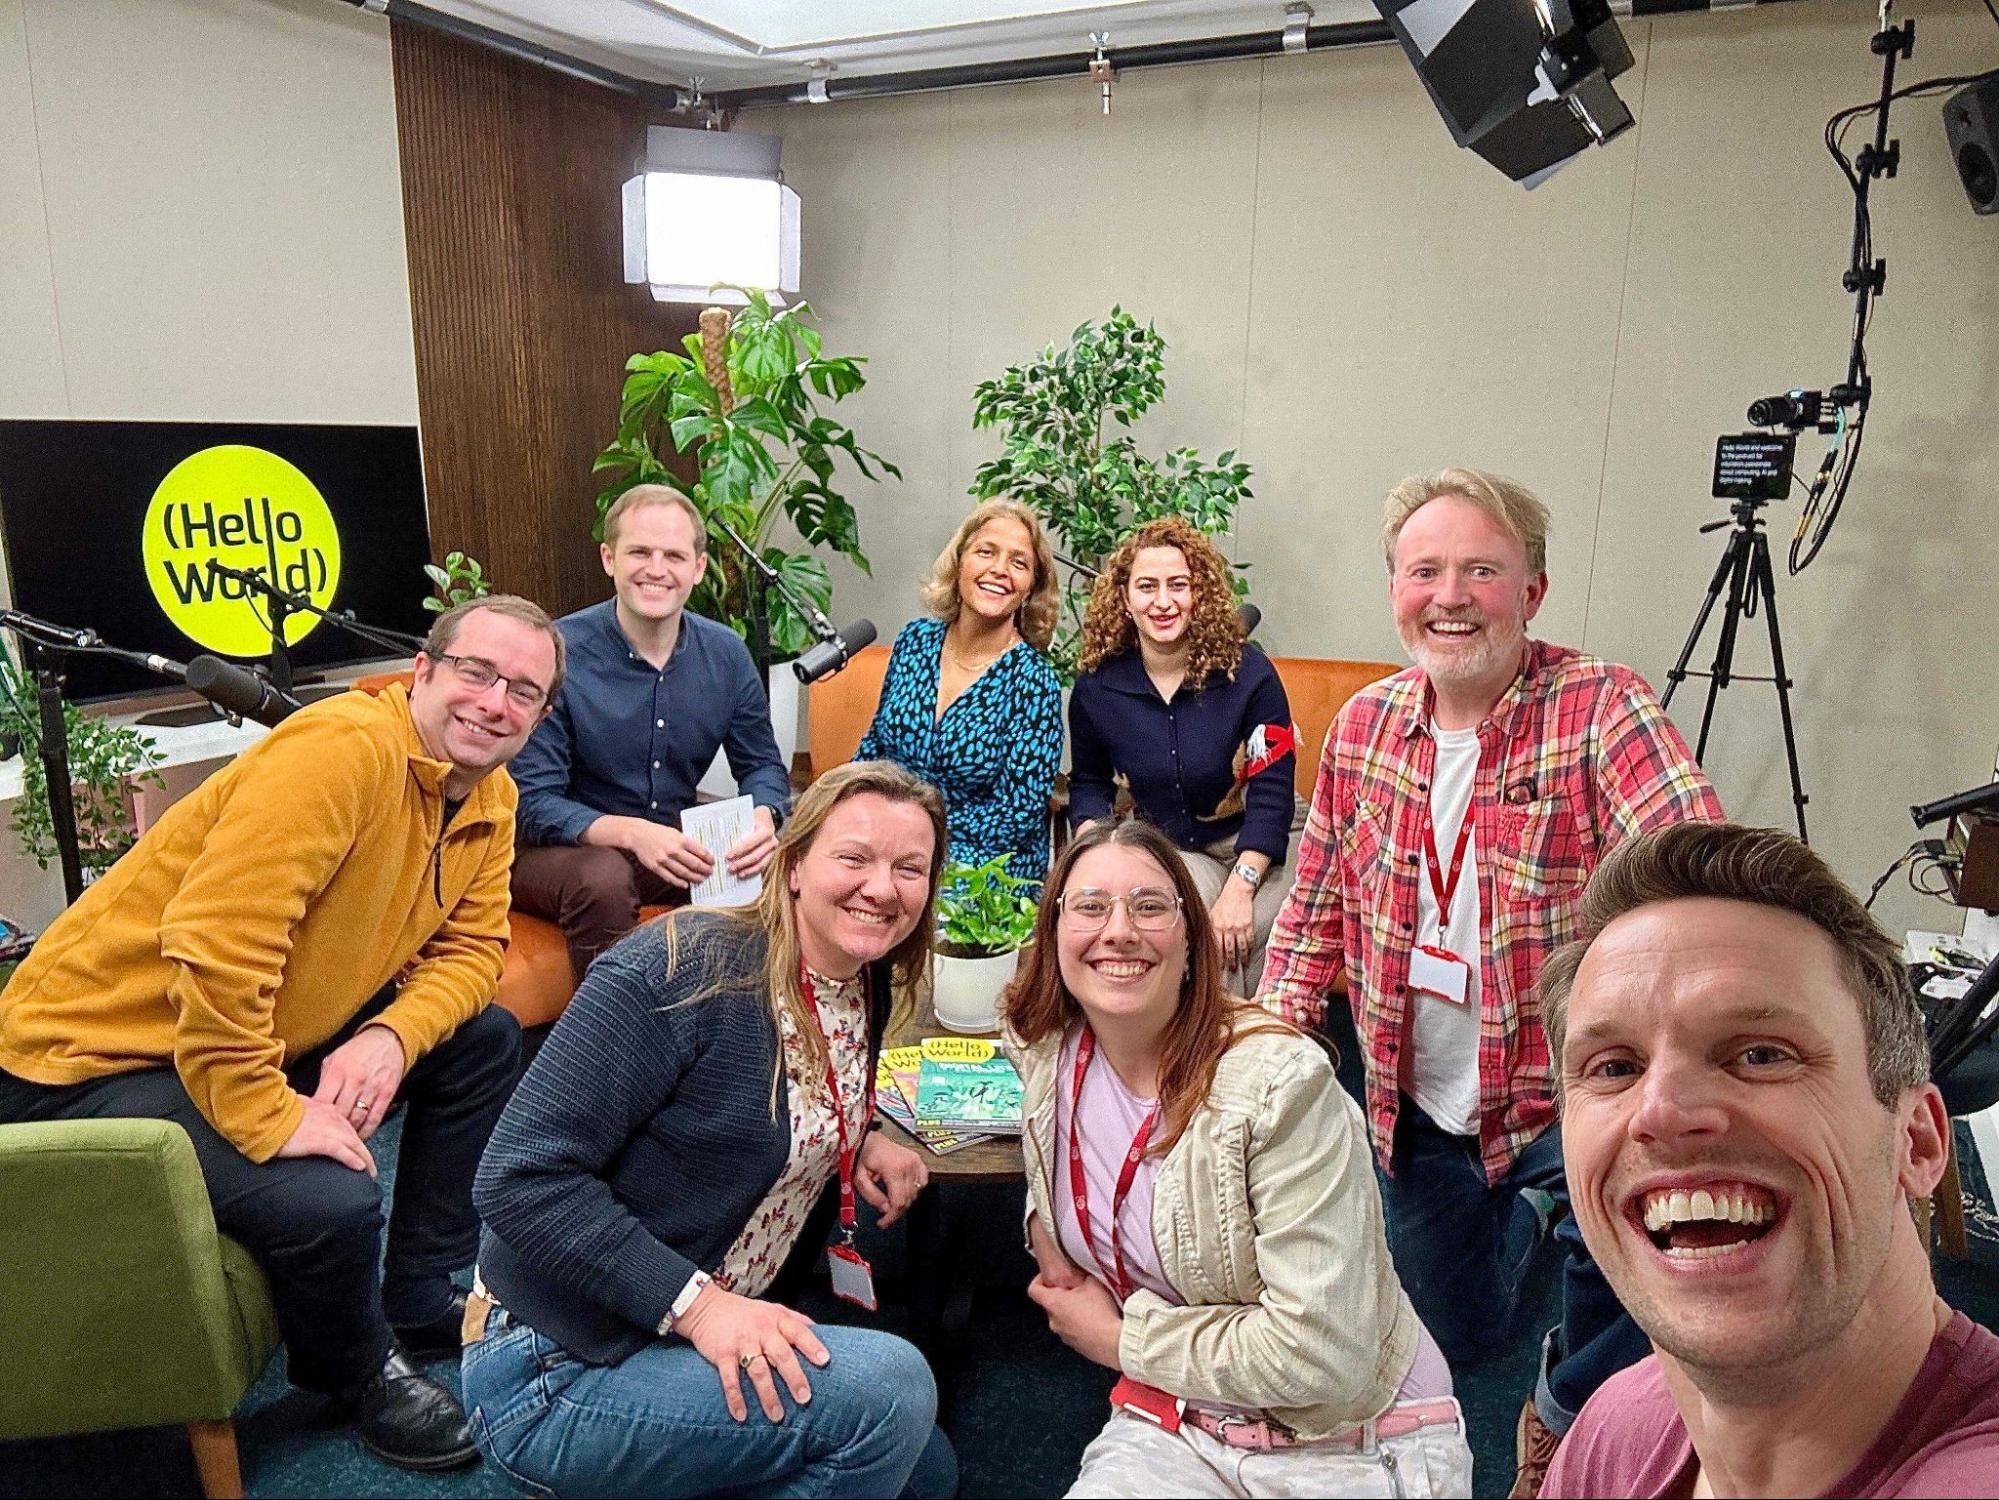
The podcast is framed around three major themes that defined 2025: data science, AI literacy, and digital literacy, all of which continue to play an increasingly important role in education systems worldwide.
Looking back at 2025
In the podcast, Rehana reflects on a year characterised by research, collaboration, and community, highlighting the importance of global partnerships in developing and localising AI literacy resources for diverse educational contexts.
From a research perspective, Bobby explains that 2025 was about pulling together what we already know and making sense of it, to better understand what good data science education should look like, including curriculum design, pedagogy, and appropriate tools.
Laura focuses on resilience and creativity in computing education, as well as the growing presence of more personalised forms of artificial intelligence, which present both significant opportunities and complex ethical challenges.

A key concern raised throughout the episode is the risk of cognitive offloading, whereby learners rely on AI tools to bypass critical thinking processes. The speakers emphasise the need for learning experiences and assessments that value process, reasoning, and reflection rather than solely final outputs.
The episode also examines barriers to the adoption of computing and AI education, including teacher confidence, limited access to devices, restrictive school IT policies, and the need for translated and localised resources.
Contributions from our colleagues around the world highlight stark contrasts in educational contexts, with challenges such as funding constraints, connectivity issues, and teacher training needs, alongside examples of innovation where educators are adequately supported.
What’s ahead
Looking ahead to 2026, Rehana outlines the potential of interdisciplinary approaches to AI literacy, integrating AI concepts into subjects such as geography, history, languages, and the arts to increase relevance and engagement (look out for our upcoming research seminar series on the topic).
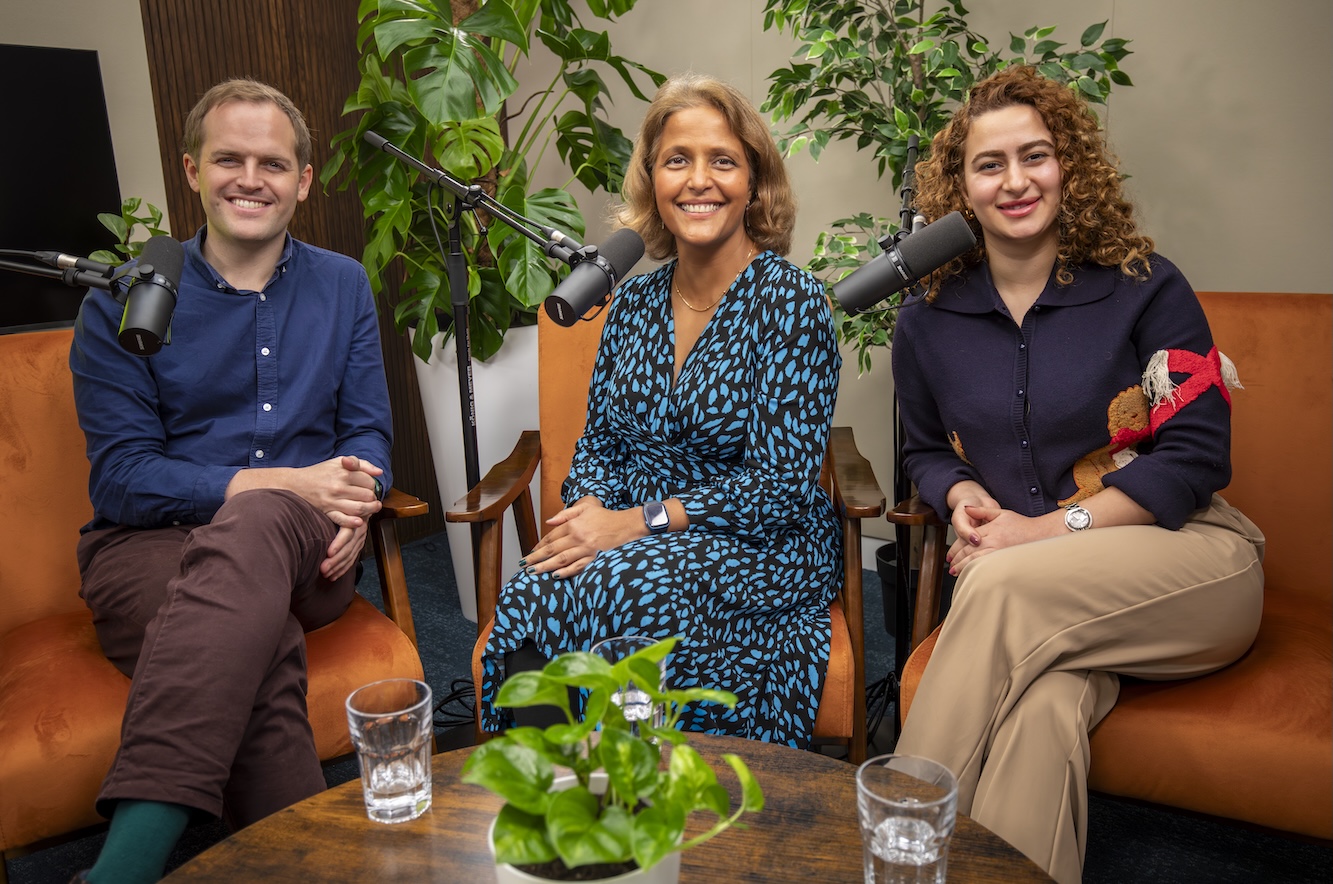
Bobby anticipates a gradual shift towards more data-informed approaches to computing education, with greater emphasis on classroom-based trials and research that directly informs practice.
Laura offers a strong call to renew focus on cybersecurity education, arguing that security and safety must remain central as digital systems and AI technologies continue to evolve.
In a series of concise predictions, the speakers point to increased attention on explainable AI, wider integration of AI literacy across the curriculum, and renewed concern for digital safety and security.
More from Hello World
You can subscribe to Hello World and listen to the full podcast episodes from wherever you get your podcasts. Or you can find this and previous Hello World podcasts on our podcast page.
Also check out Hello World magazine, our free digital and print magazine from computing educators for computing educators.
The post What shaped computing education in 2025 — and what comes next appeared first on Raspberry Pi Foundation.
Comic for 2026.01.07 – Revealing Dress
Post Syndicated from Explosm.net original https://explosm.net/comics/revealing-dress
New Cyanide and Happiness Comic
AMD Teases Ryzen AI Halo, a ROCm Ecosystem AI Development Mini-PC
Post Syndicated from Ryan Smith original https://www.servethehome.com/amd-teases-ryzen-ai-halo-a-rocm-ecosystem-ai-development-mini-pc/
Among a spate of AMD announcements during the company’s CES 2026 opening keynote, CEO Dr. Lisa Su briefly teased a forthcoming AMD-branded AI development box, dubbed the Ryzen AI Halo. Seemingly taking a page from similar AI development boxes that have popped up over the last year – both those built using AMD’s hardware and […]
The post AMD Teases Ryzen AI Halo, a ROCm Ecosystem AI Development Mini-PC appeared first on ServeTheHome.
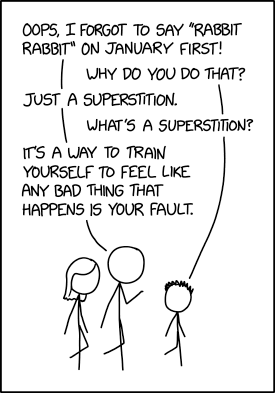
Superstition
Post Syndicated from xkcd.com original https://xkcd.com/3191/
Amazon EMR Serverless eliminates local storage provisioning, reducing data processing costs by up to 20%
Post Syndicated from Karthik Prabhakar original https://aws.amazon.com/blogs/big-data/amazon-emr-serverless-eliminates-local-storage-provisioning-reducing-data-processing-costs-by-up-to-20/
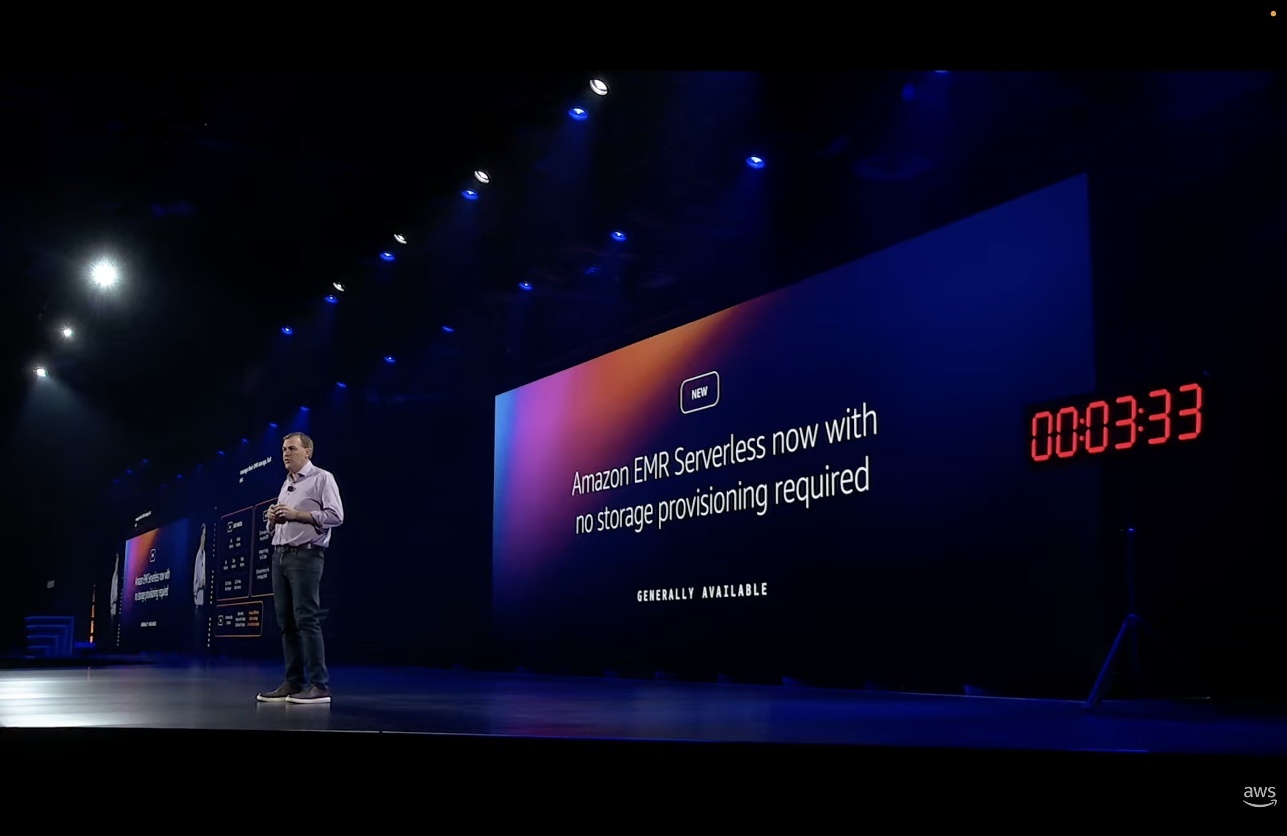
At AWS re:Invent 2025, Amazon Web Services (AWS) announced serverless storage for Amazon EMR Serverless, a new capability that eliminates the need configure local disks for Apache Spark workloads. This reduces data processing costs by up to 20% while eliminating job failures from disk capacity constraints.
With serverless storage, Amazon EMR Serverless automatically handles intermediate data operations, such as shuffle, on your behalf. You pay only for compute and memory—no storage charges. By decoupling storage from compute, Spark can release idle workers immediately, reducing costs throughout the job lifecycle. The following image shows the serverless storage for EMR Serverless announcement from the AWS re:Invent 2025 keynote:
The challenge: Sizing local disk storage
Running Apache Spark workloads requires sizing local disk storage for shuffle operations—where Spark redistributes data across executors during joins, aggregations, and sorts. This requires analyzing job histories to estimate disk requirements, leading to two common problems: overprovisioning wastes money on unused capacity, and under provisioning causes job failures when disk space runs out. Most customers overprovision local storage to ensure jobs complete successfully in production.
Data skew compounds this further. When one executor handles a disproportionately large partition, that executor takes significantly longer to complete while other workers sit idle. If you didn’t provision enough disk for that skewed executor, the job fails entirely—making data skew one of the top causes of Spark job failures. However, the problem extends beyond capacity planning. Because shuffle data couples tightly to local disks, Spark executors pin to worker nodes even when compute requirements drop between job stages. This prevents Spark from releasing workers and scaling down, inflating compute costs throughout the job lifecycle. When a worker node fails, Spark must recompute the shuffle data stored on that node, causing delays and inefficient resource usage.
How it works
Serverless storage for Amazon EMR Serverless addresses these challenges by offloading shuffle operations from individual compute workers onto a separate, elastic storage layer. Instead of storing critical data on local disks attached to Spark executors, serverless storage automatically provisions and scales high-performance remote storage as your job runs.
The architecture provides several key benefits. First, compute and storage scale independently—Spark can acquire and release workers as needed across job stages without worrying about preserving locally stored data. Second, shuffle data is evenly distributed across the serverless storage layer, eliminating data skew bottlenecks that occur when some executors handle disproportionately large shuffle partitions. Third, if a worker node fails, your job continues processing without delays or reruns because data is reliably stored outside individual compute workers.
Serverless storage is provided at no additional charge, and it eliminates the cost associated with local storage. Instead of paying for fixed disk capacity sized for maximum potential I/O load—capacity that often sits idle during lighter workloads—you can use serverless storage without incurring storage costs. You can focus your budget on compute resources that directly process your data, not on managing and overprovisioning disk storage.
Technical innovation brings three breakthroughs
Serverless storage introduces three fundamental innovations that solve Spark’s shuffle bottlenecks: multi-tier aggregation architecture, purpose-built networking, and true storage-compute decoupling. Apache Spark’s shuffle mechanism has a core constraint: each mapper independently writes output as small files, and each reducer must fetch data from potentially thousands of workers. In a large-scale job with 10,000 mappers and 1,000 reducers, this creates 10 million individual data exchanges. Serverless storage aggregates early and intelligently—mappers stream data to an aggregation layer that consolidates shuffle data in memory before committing to storage. Whereas individual shuffle write and fetch operations might show slightly higher latency due to network round-trips compared to local disk I/O, the overall job performance improves by transforming millions of tiny I/O operations into a smaller number of large, sequential operations.
Traditional Spark shuffle creates a mesh network where each worker maintains connections to potentially hundreds of other workers, spending significant CPU on connection management rather than data processing. We built a custom networking stack where each mapper opens a single persistent remote procedure call (RPC) connection to our aggregator layer, eliminating the mesh complexity. Although individual shuffle operations might show slightly higher latency due to network round trips compared to local disk I/O, overall job performance improves through better resource utilization and elastic scaling. Workers no longer run a shuffle service—they focus entirely on processing your data.
Traditional Amazon EMR Serverless jobs store shuffle data on local disks, coupling data lifecycle to worker lifecycle—idle workers can’t terminate without losing shuffle data. Serverless storage decouples these entirely by storing shuffle data in AWS managed storage with opaque handles tracked by the driver. Workers can terminate immediately after completing tasks without data loss, enabling elastic scaling. In funnel-shaped queries where early stages require massive parallelism that narrows as data aggregates, we’re seeing up to 80% compute cost reduction in benchmarks by releasing idle workers instantly. The following diagram illustrates instant worker release in funnel-shaped queries.
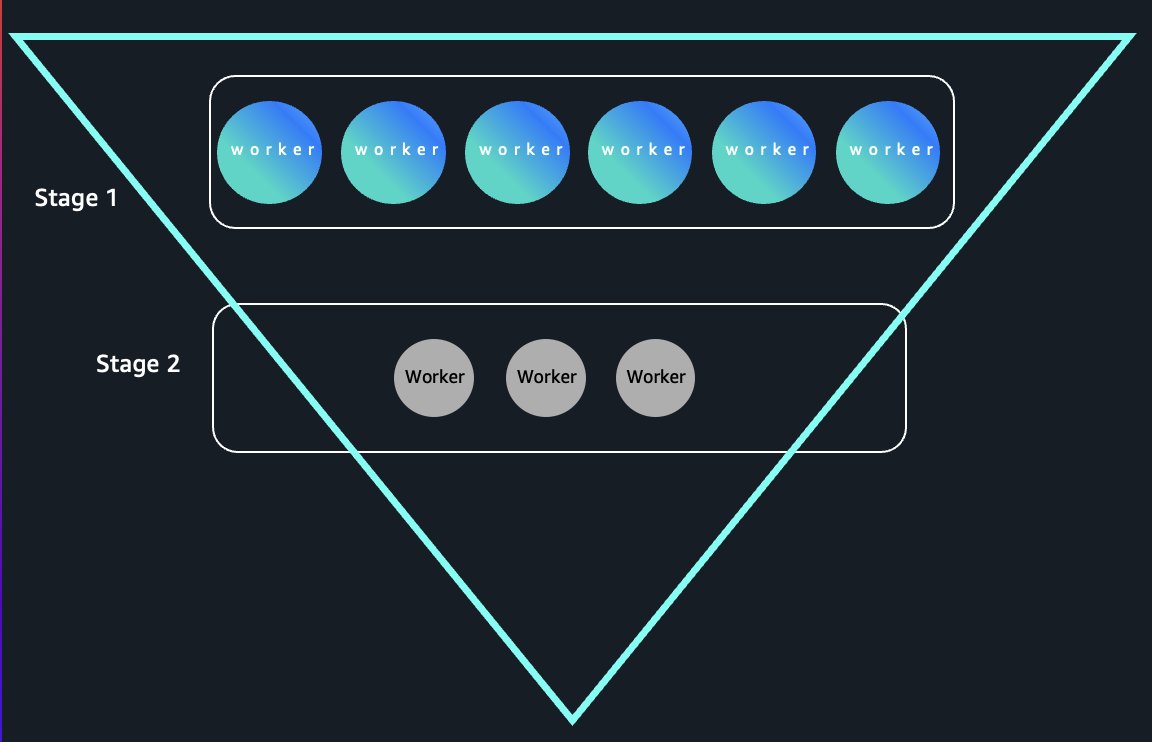
Our aggregator layer integrates directly with AWS Identity and Access Management (IAM), AWS Lake Formation, and fine-grained access control systems, providing job-level data isolation with access controls that match source data permissions.
Getting started
Serverless storage is available in multiple AWS Regions. For the current list of supported Regions, refer to the Amazon EMR User Guide.
New applications
Serverless storage can be enabled for new applications starting with Amazon EMR release 7.12. Follow these steps:
- Create an Amazon EMR Serverless application with Amazon EMR 7.12 or later:
- Submit your Spark job:
Existing applications
You can enable serverless storage for existing applications on Amazon EMR 7.12 or later by updating your application settings.
To enable serverless storage using AWS Command Line Interface (AWS CLI), enter the following command:
To enable serverless storage using Amazon EMR Studio UI, navigate to your application in Amazon EMR Studio, go to Configuration, and add the Spark property spark.aws.serverlessStorage.enabled=true in the spark-defaults classification.
Job-level configuration
You can also enable serverless storage for specific jobs, even when it’s not enabled at the application level:
(Optional) Disabling serverless storage
If you prefer to continue using local disks, you can disable serverless storage by omitting the spark.aws.serverlessStorage.enabled configuration or setting it to false at either the application or job level:
spark.aws.serverlessStorage.enabled=falseTo use traditional local disk provisioning, configure the appropriate disk type and size for your application workers.
Monitoring and cost tracking
You can monitor elastic shuffle usage through standard Spark UI metrics and track costs at the application level in AWS Cost Explorer and AWS Cost and Usage Reports. The service automatically handles performance optimization and scaling, so you don’t need to tune configuration parameters.
When to use serverless storage
Serverless storage delivers the most value for workloads with substantial shuffle operations—typically jobs that shuffle more than 10 GB of data (and less than 200 G per job, the limitation as of this writing). These include:
- Large-scale data processing with heavy aggregations and joins
- Sort-heavy analytics workloads
- Iterative algorithms that repeatedly access the same datasets
Jobs with unpredictable shuffle sizes benefit particularly well because serverless storage automatically scales capacity up and down based on real-time demand. For workloads with minimal shuffle activity or very short duration (under 2–3 minutes), the benefits might be limited. In these cases, the overhead of remote storage access might outweigh the advantages of elastic scaling.
Security and data lifecycle
Your data is stored in serverless storage only while your job is running and is automatically deleted when your job is completed. Because Amazon EMR Serverless batch jobs can run for up to 24 hours, your data will be stored for no longer than this maximum duration. Serverless storage encrypts your data both in transit between your Amazon EMR Serverless application and the serverless storage layer and at rest while temporarily stored, using AWS managed encryption keys. The service uses an IAM based security model with job-level data isolation, which means that one job can’t access the shuffle data of another job. Serverless storage maintains the same security standards as Amazon EMR Serverless, with enterprise-grade security controls throughout the processing lifecycle.
Conclusion
Serverless storage represents a fundamental shift in how we approach data processing infrastructure, eliminating manual configuration, aligning costs to actual usage, and improving reliability for I/O intensive workloads. By offloading shuffle operations to a managed service, data engineers can focus on building analytics rather than managing storage infrastructure.
To learn more about serverless storage and get started, visit the Amazon EMR Serverless documentation.
About the authors
Building scalable AWS Lake Formation governed data lakes with dbt and Amazon Managed Workflows for Apache Airflow
Post Syndicated from Abhilasha Agarwal original https://aws.amazon.com/blogs/big-data/building-scalable-aws-lake-formation-governed-data-lakes-with-dbt-and-amazon-managed-workflows-for-apache-airflow/
Organizations often struggle with building scalable and maintainable data lakes—especially when handling complex data transformations, enforcing data quality, and monitoring compliance with established governance. Traditional approaches typically involve custom scripts and disparate tools, which can increase operational overhead and complicate access control. A scalable, integrated approach is needed to simplify these processes, improve data reliability, and support enterprise-grade governance.
Apache Airflow has emerged as a powerful solution for orchestrating complex data pipelines in the cloud. Amazon Managed Workflows for Apache Airflow (MWAA) extends this capability by providing a fully managed service that eliminates infrastructure management overhead. This service enables teams to focus on building and scaling their data workflows while AWS handles the underlying infrastructure, security, and maintenance requirements.
dbt enhances data transformation workflows by bringing software engineering best practices to analytics. It enables analytics engineers to transform warehouse data using familiar SQL select statements while providing essential features like version control, testing, and documentation. As part of the ELT (Extract, Load, Transform) process, dbt handles the transformation phase, working directly within a data warehouse to enable efficient and reliable data processing. This approach allows teams to maintain a single source of truth for metrics and business definitions while enabling data quality through built-in testing capabilities.
In this post, we show how to build a governed data lake that uses modern data tools and AWS services.
Solution overview
We explore a comprehensive solution that includes:
- A metadata-driven framework in MWAA that dynamically generates directed acyclic graphs (DAGs), significantly improving pipeline scalability and reducing maintenance overhead.
- dbt with Amazon Athena adapter to implement modular, SQL-based data transformations directly on a data lake, enabling well-structured, and thoroughly tested transformations.
- An automated framework that proactively identifies and segregates problematic records, maintaining the integrity of data assets.
- AWS Lake Formation to implement fine-grained access controls for Athena tables, ensuring proper data governance and security throughout a data lake environment.
Together, these components create a robust, maintainable, and secure data management solution suitable for enterprise-scale deployments.
The following architecture illustrates the components of the solution.

The workflow contains the following steps:
- Multiple data sources (PostgreSQL, MySQL, SFTP) push data to an Amazon S3 raw bucket
- S3 event triggers AWS Lambda Function
- Lambda function triggers the MWAA DAG to convert file formats to parquet
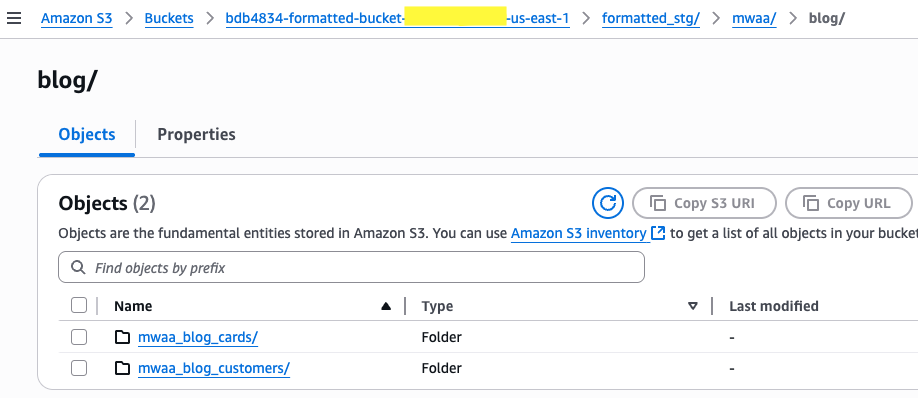
- Data is stored in Amazon S3 formatted bucket under formatted_stg prefix
- Crawler crawls the data in formatted_stg prefix in the formatted bucket and creates catalog tables
- dbt using Athena adapter processes the data and puts the processed data after data quality checks under formatted prefix in Formatted bucket
- dbt using Athena adapter can perform further transformations on the formatted data and put the transformed data in Published bucket
Prerequisites
To implement this solution, the following prerequisites need to be met.
- An AWS account with create/operate access for the following AWS services:
Deploy the solution
For this solution, we provide an AWS CloudFormation (CFN) template that sets up the services included in the architecture, to enable repeatable deployments.
Note:
- US-EAST-1 Region is required for the deployment.
- Deploying this solution will involve costs associated with AWS services.
To deploy the solution, complete the following steps:
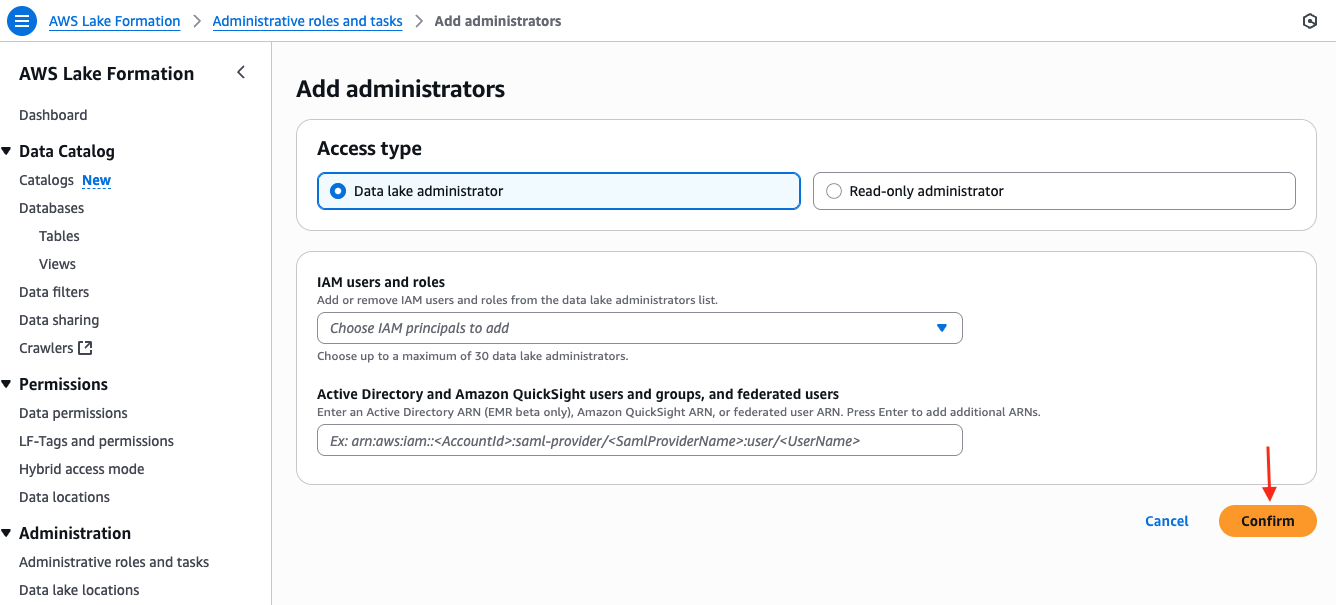
- Before deploying the stack, open the AWS Lake Formation console. Add your console role as a Data Lake Administrator and choose Confirm to save the changes.

- Download the CloudFormation template.
After the file is downloaded to the local machine, follow the steps below to deploy the stack using this template:- Open the AWS CloudFormation Console.
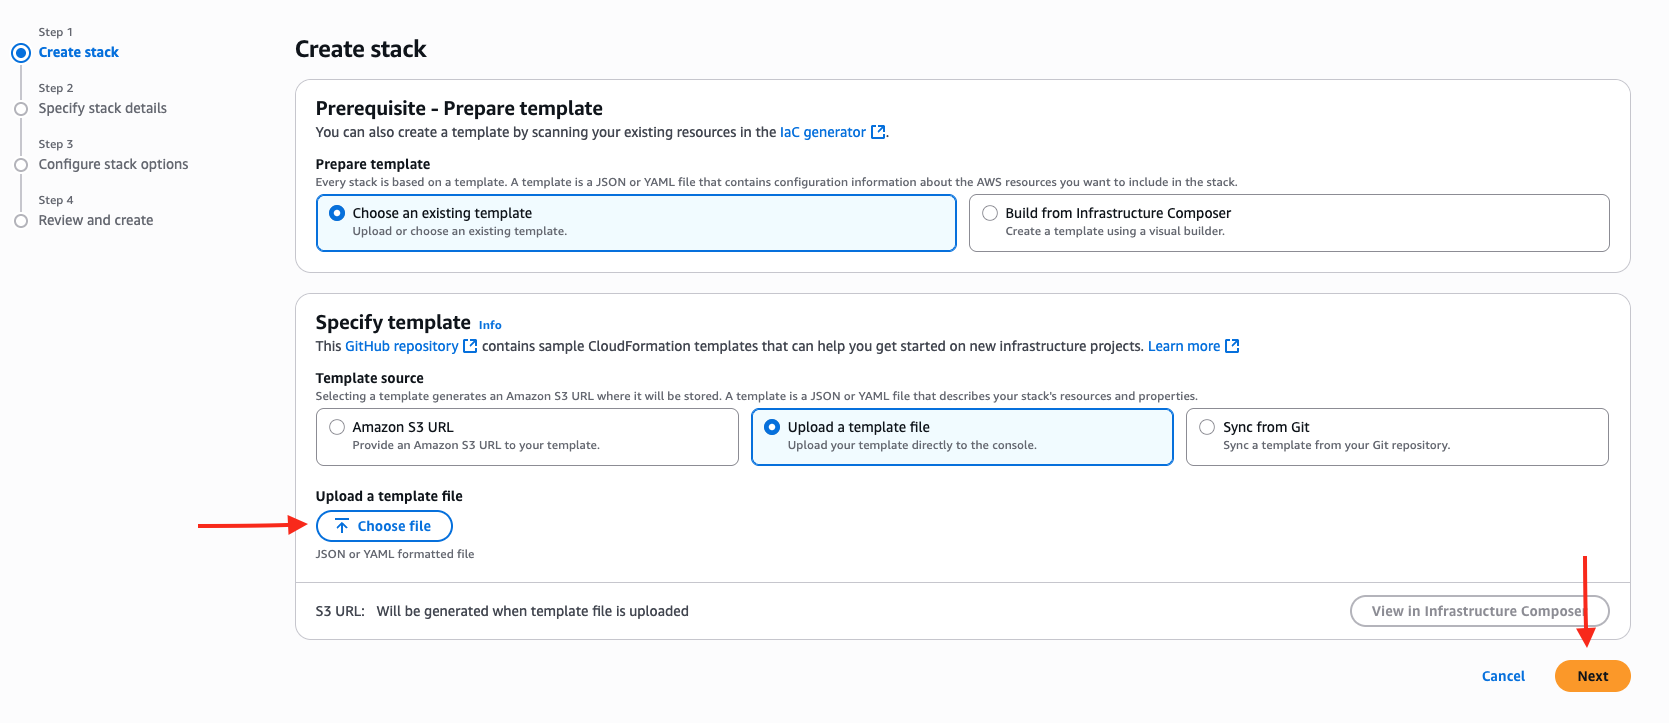
- Choose Create stack and choose With new resources (standard).
- Under Specify template, select Upload a template file.
- Select Choose file and upload the CFN template that was downloaded earlier.
- Choose Next to proceed.

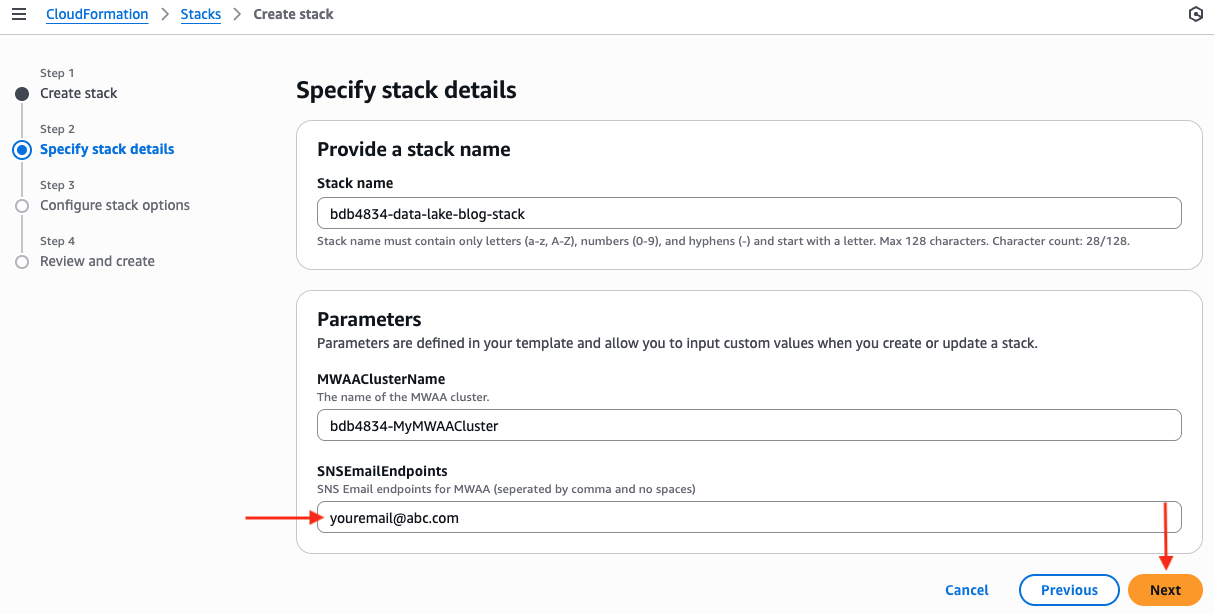
- Enter a stack name (for example, bdb4834-data-lake-blog-stack) and configure the parameters (bdb4834-MWAAClusterName can be left as the default value and update SNSEmailEndpoints with your email address), then choose Next.

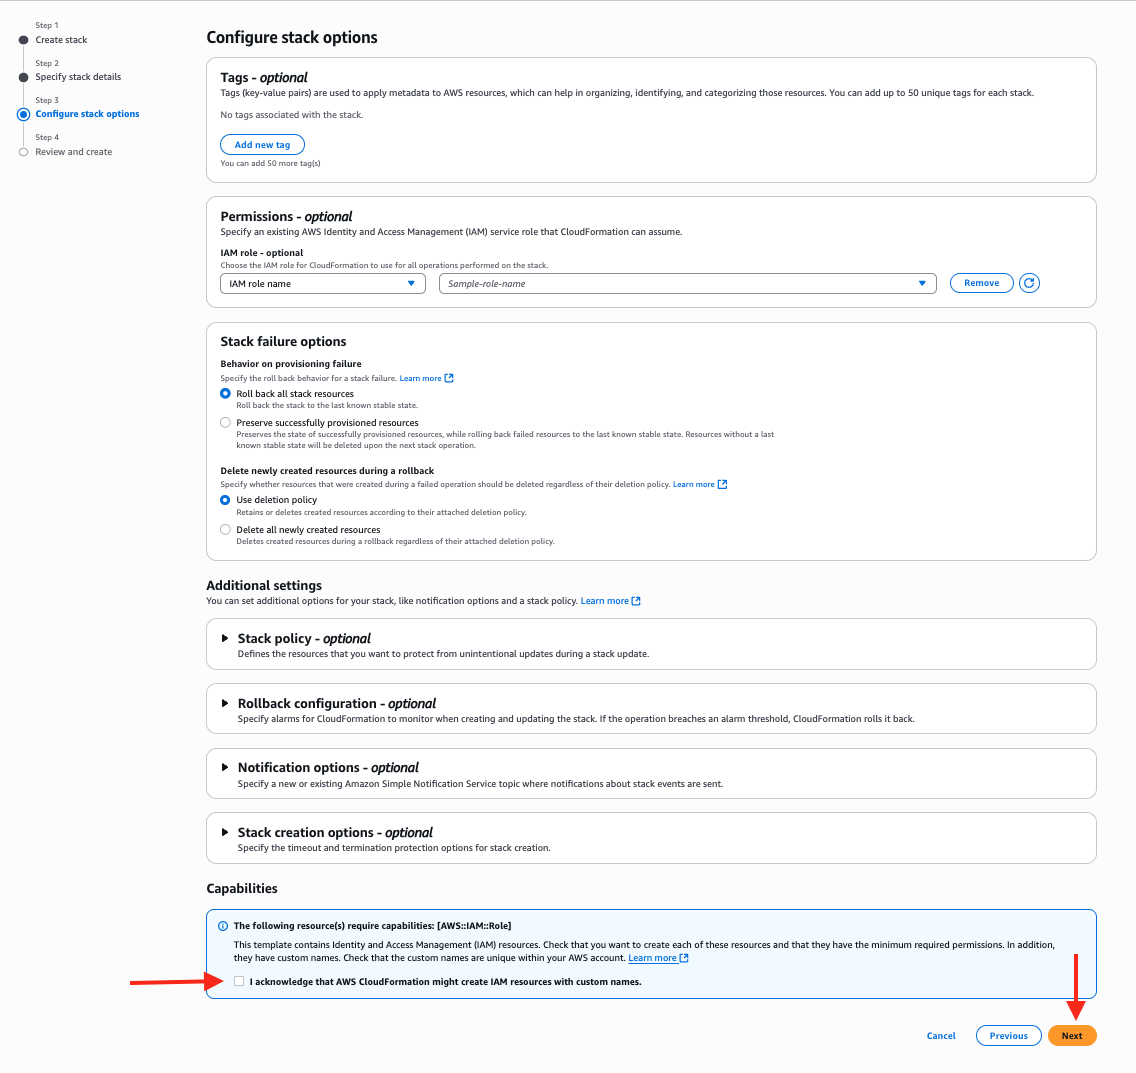
- Select “I acknowledge that AWS CloudFormation might create IAM resources with custom names” and choose Next

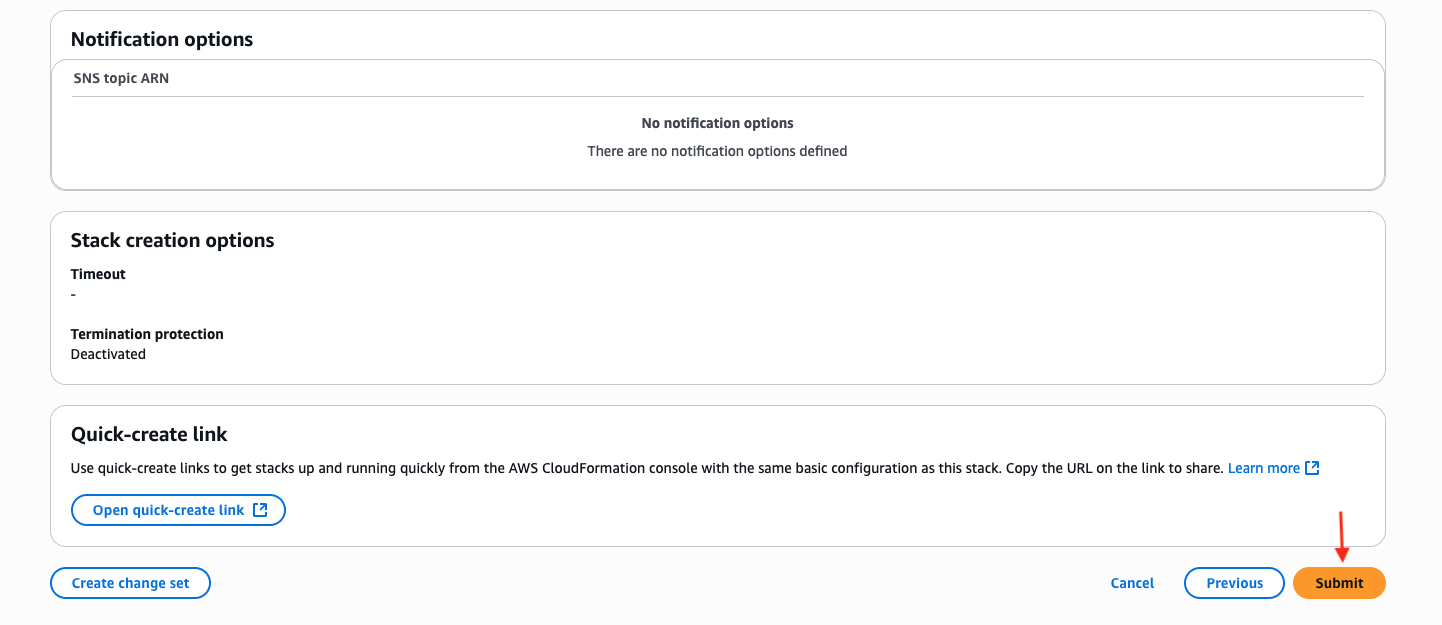
- Review all the configuration details on the next page, then choose Submit.

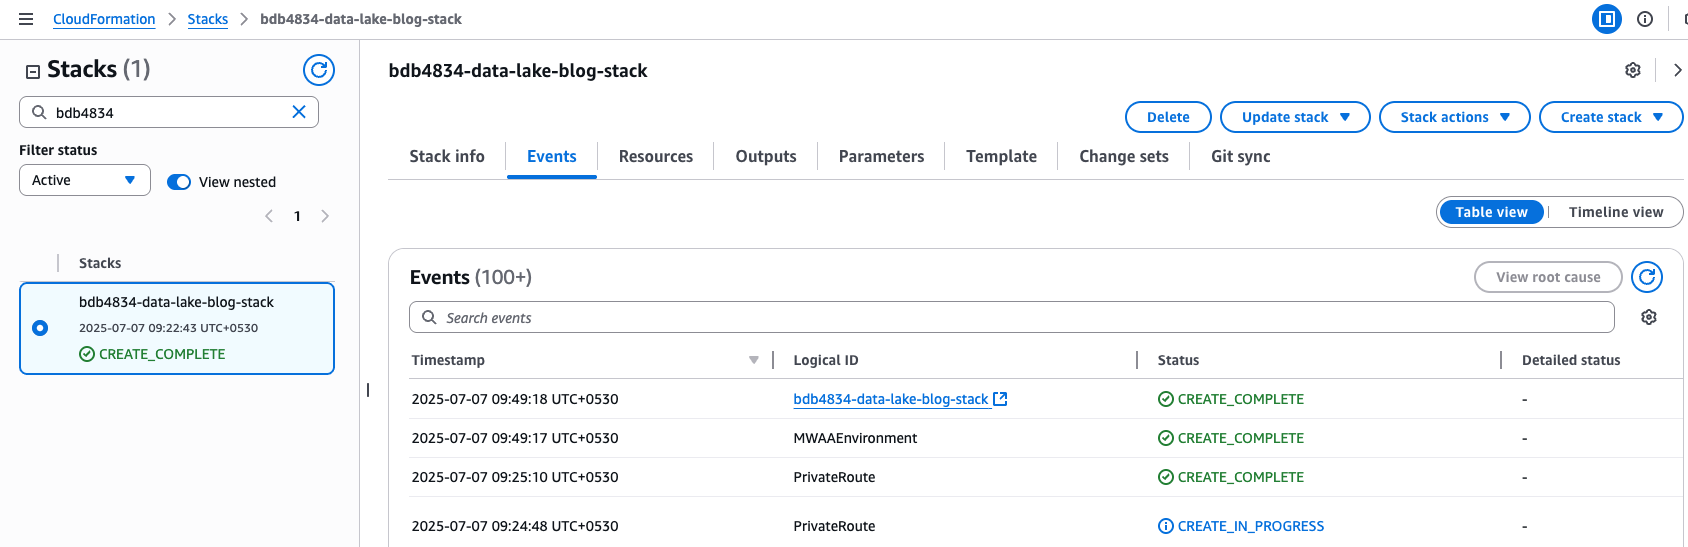
- Wait for the stack creation to complete in the AWS CloudFormation console. The process typically takes approximately 35 to 40 minutes to provision all required resources.

The following table shows resources available in the AWS Account after CloudFormation template deployment is successfully completed:
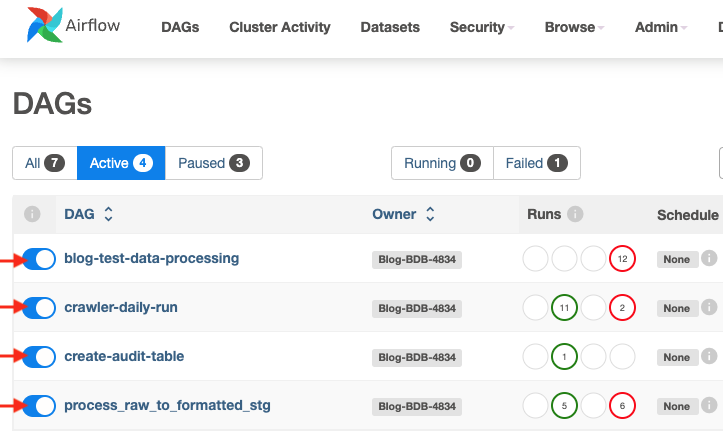
Resource Type Description Example Resource Name S3 Buckets For storing raw, processed data and assets bdb4834-mwaa-bucket-<AWS_ACCOUNT>-<AWS_REGION>,bdb4834-raw-bucket-<AWS_ACCOUNT>-<AWS_REGION>,bdb4834-formatted-bucket-<AWS_ACCOUNT>-<AWS_REGION>,bdb4834-published-bucket-<AWS_ACCOUNT>-<AWS_REGION> IAM Role Role assumed by MWAA for permissions bdb4834-mwaa-role MWAA Environment Managed Airflow environment for orchestration bdb4834-MyMWAACluster VPC Network setup required by MWAA bdb4834-MyVPC Glue Catalog Databases Logical grouping of metadata for tables bdb4834_formatted_stg,bdb4834_formatted_exception, bdb4834_formatted, bdb4834_published Glue Crawlers Automatically catalog metadata from S3 bdb4834-formatted-stg-crawler Lambda Lambda to Trigger MWAA DAG on file arrival and to setup Lake Formation Permissions bdb4834_mwaa_trigger_process_s3_files,bdb4834-lf-tags-automation Lake Formation Setup Centralized governance and permissions LF-Setup for the above Resources Airflow DAGs Airflow DAGs are stored in the S3 bucket named mwaa-bucket-<AWS_ACCOUNT>-<AWS_REGION> under the dags/ prefix. These DAGs are responsible for triggering data pipelines based on either file arrival events or scheduled intervals. The exact functionality of each DAG is explained in the following sections. blog-test-data-processingcrawler-daily-runcreate-audit-tableprocess_raw_to_formatted_stage - When the stack is complete perform the below steps:
- Open the Amazon Managed Workflows for Apache Airflow (MWAA) console, choose on Open Airflow UI
- In the DAGs console, locate the following DAGs and unpause them by unchecking the toggle switch (radio button) next to each DAG.
Add sample data to raw S3 bucket and create catalog tables
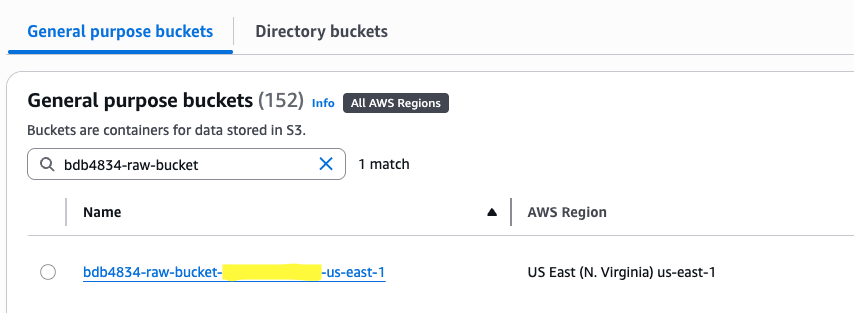
In this section, we upload sample data to raw S3 bucket (bucket name starting with bdb4834-raw-bucket) and convert the file formats to parquet and run AWS Glue crawler to create catalog tables that are used by dbt in the ELT Process. Glue Crawler automatically scans the data in S3 and creates or updates tables in the Glue Data Catalog, making the data queryable and accessible for transformation.
- Download the sample data.
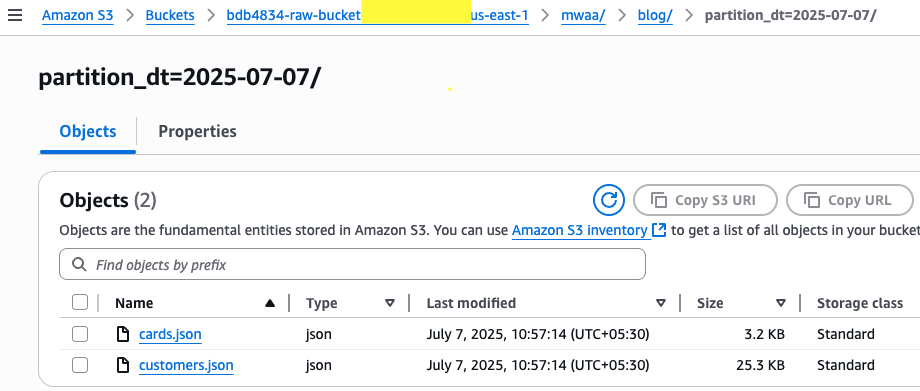
- Zip folder contains two sample data files, cards.json and customers.json
Schema for cards.jsonField Data Type Description cust_id String Unique customer identifier cc_number String Credit card number cc_expiry_date String Credit card expiry date Schema for customers.json
Field Data Type Description cust_id String Unique customer identifier fname String First name lname String Last name gender String Gender address String Full address dob String Date of birth (YYYY/MM/DD) phone String Phone number email String Email address - Open S3 console, choose General purpose buckets in the navigation pane.
- Locate the S3 bucket with a name starting with bdb4834-raw-bucket. This bucket is created by the CloudFormation stack and can also be found under the stack’s Resources tab in the CloudFormation console.

- Choose the bucket name to open it, and follow these steps to create the required prefix:
- Choose Create folder.
- Enter the folder name as mwaa/blog/partition_dt=YYYY-MM-DD/, replacing YYYY-MM-DD with the actual date to be used for the partition.
- Choose Create folder to confirm.
- Upload the sample data files from the location to the s3 raw bucket prefix.

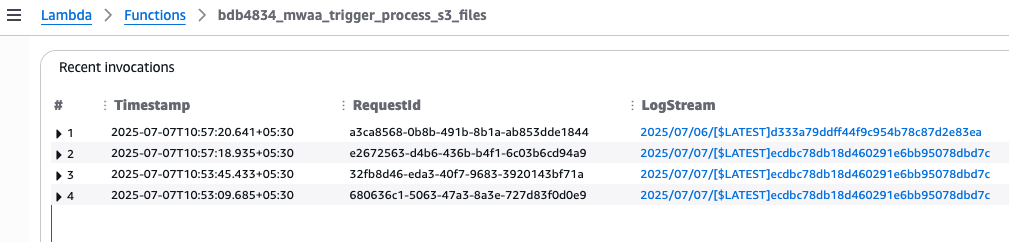
- As soon as the files are uploaded, the on_put object event on the raw bucket invokes
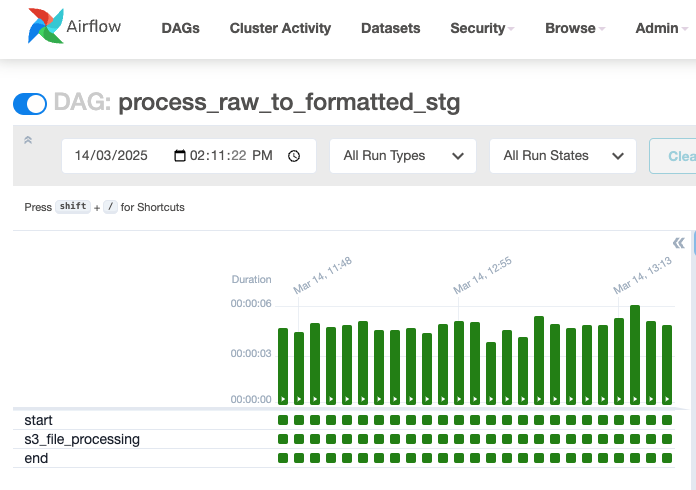
thebdb4834_mwaa_trigger_process_s3_fileslambda which triggers the process_raw_to_formatted_stg MWAA DAG.- In the Airflow UI, choose the process_raw_to_formatted_stg DAG to view execution status. This DAG converts the file formats to parquet and typically completes within a few seconds.

- (Optional) To check the Lambda execution details:
- On the AWS Lambda Console, choose Functions in the navigation pane.
- Select the function named bdb4834_mwaa_trigger_process_s3_files.

- In the Airflow UI, choose the process_raw_to_formatted_stg DAG to view execution status. This DAG converts the file formats to parquet and typically completes within a few seconds.
- Validate the parquet files are created in formatted bucket (bucket name starting with
bdb4834-formatted) under the respective data object prefix.

- Before proceeding further, re-upload the Lake Formation metadata file in MWAA bucket.
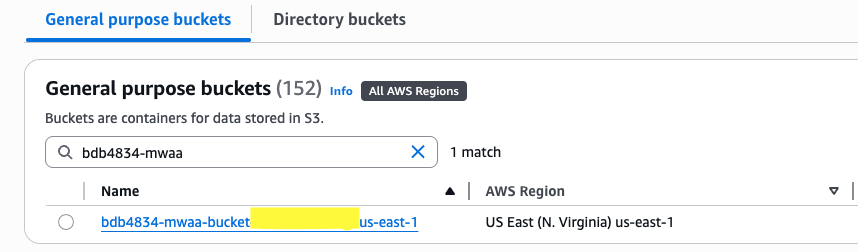
- Open the S3 console, choose General purpose buckets in the navigation pane.
- Search for the bucket starting with bdb4834-mwaa-bucket

- Choose the bucket name and go to the lakeformation prefix. Download the file named
lf_tags_metadata.json. Now, re-upload the same file to the same location.
Note: This re-upload is necessary because the Lambda function is configured to trigger on file arrival. When the resources were initially created by the CloudFormation stack, the files were simply moved to S3 and did not trigger the Lambda. Re-uploading the file ensures the Lambda function is executed as intended. - As soon as the file is uploaded, the on_put object event on the MWAA bucket invokes the lf_tags_automation lambda, which creates the Lake Formation (LF) tags as defined in the metadata file and grants access to the specified AWS Identity and Access Management (IAM) roles for read/write.
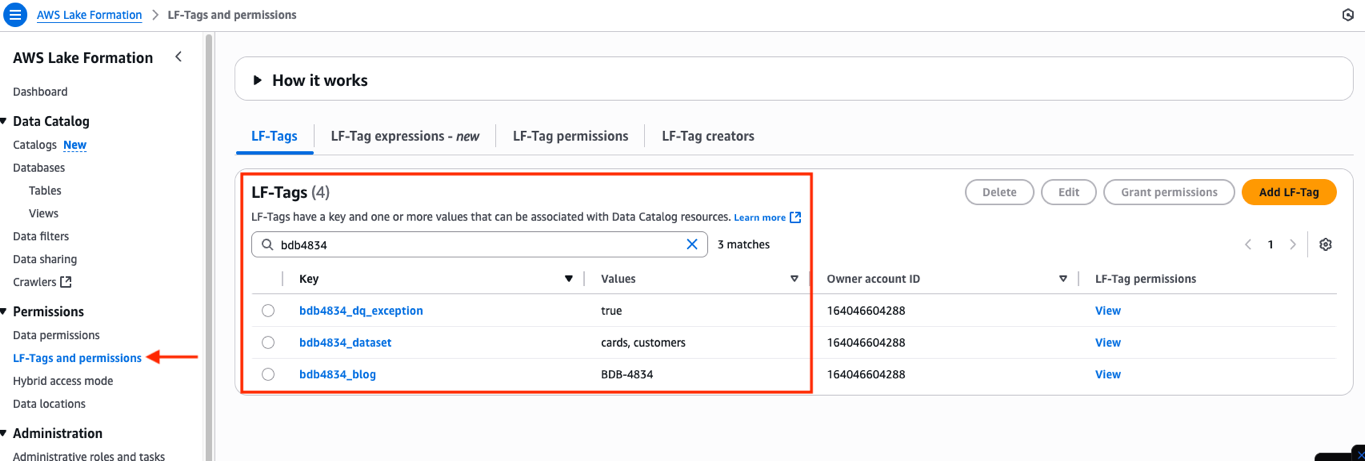
- Validate that the LF-Tags have been created by visiting the Lake Formation Console. In the left navigation pane, choose Permissions, and then select LF-Tags and permissions.

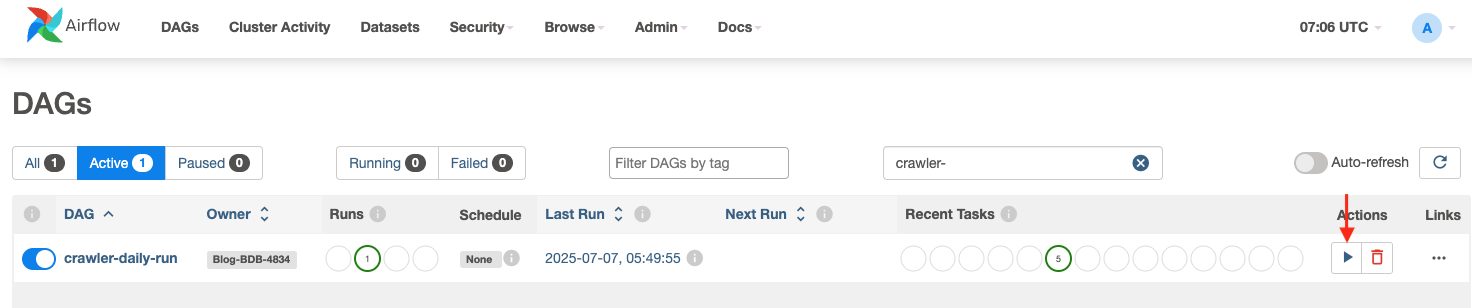
- Now, run the crawler DAG to create/update the catalog tables:
crawler-daily-run- In the Airflow UI select the
crawler-daily-runDAG and choose Trigger DAG to execute it. - This DAG is configured to trigger Glue Crawler which crawls the
formatted_stgprefix under thebdb4834-formatteds3 bucket to create catalog tables as per the prefixes available under theformatted_stgprefix.
- Monitor the execution of the crawler-daily-run DAG until it completes, which typically takes 2 to 3 minutes. The crawler run status can be verified in the AWS Glue Console by following these steps:
- Open the AWS Glue Console.
- In the left navigation pane, choose Crawlers.
- Search for the crawler named
bdb4834-formatted-stg-crawler. - Check the Last run status column to confirm the crawler executed successfully.
- Choose the crawler name to view additional run details and logs if needed.

- Once the crawler has completed successfully, in the left-hand panel, choose Databases and select the bdb4834_formatted_stg database to view the created tables, which should appear as showing in the following image. Optionally, select the table’s name to view its schema, and then select Table data to open Athena for data analysis. (An error may appear when querying data using Athena due to Lake Formation permissions. Review the Governance using Lake Formation section in this post to resolve the issue.)
- In the Airflow UI select the
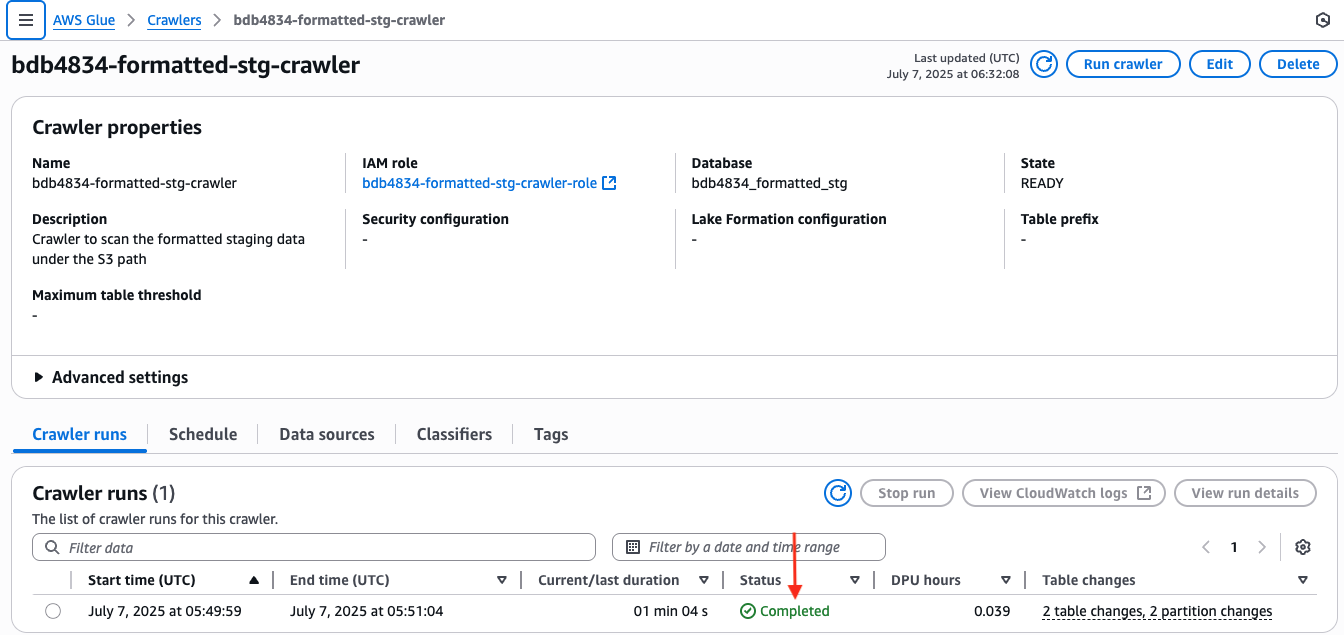
Note: If this is the first time Athena is being used, a query result location must be configured by specifying an S3 bucket. Follow the instructions in the AWS Athena documentation to set up the S3 staging bucket for storing query results.
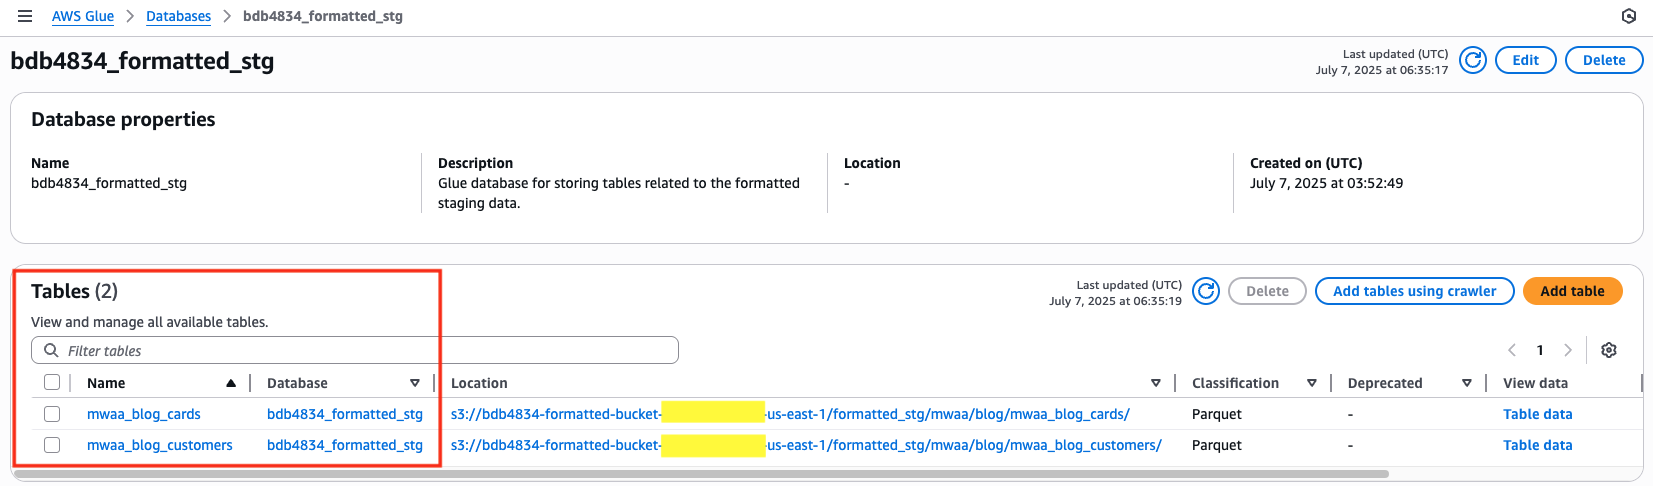
Run model through DAG in MWAA
In this section, we cover how dbt models run in MWAA using Athena adapter to create Glue-catalogued tables and how auditing is done for each run.
- After creating the tables in the Glue database using the AWS Glue Crawler in the previous steps, we can now proceed to run the dbt models in MWAA. These models are stored in S3 in the form of SQL files, located at the S3 prefix: bdb4834-mwaa-bucket-<account_id>-us-east-1/dags/dbt/models/
The following are the dbt models and their functionality:mwaa_blog_cards_exception.sqlThis model reads data from themwaa_blog_cardstable in thebdb4834_formatted_stgdatabase and writes records with data quality issues to themwaa_blog_cards_exceptiontable in thebdb4834_formatted_exceptiondatabase.mwaa_blog_customers_exception.sqlThis model reads data from themwaa_blog_customerstable in thebdb4834_formatted_stgdatabase and writes records with data quality issues to themwaa_blog_customers_exceptiontable in thebdb4834_formatted_exceptiondatabase.mwaa_blog_cards.sqlThis model reads data from themwaa_blog_cardstable in thebdb4834_formatted_stgdatabase and loads it into themwaa_blog_cardstable in thebdb4834_formatteddatabase. If the target table does not exist, dbt automatically creates it.mwaa_blog_customers.sqlThis model reads data from themwaa_blog_customerstable in thebdb4834_formatted_stgdatabase and loads it into themwaa_blog_customerstable in thebdb4834_formatteddatabase. If the target table does not exist, dbt automatically creates it.
- The
mwaa_blog_cards.sqlmodel processes credit card data and depends on themwaa_blog_customers.sqlmodel to complete successfully before it runs. This dependency is necessary because certain data quality checks—such as referential integrity validations between customer and card records—must be performed beforehand.- These relationships and checks are defined in the
schema.ymlfile located in the same S3 path:bdb4834-mwaa-bucket-<account_id>-us-east-1/dags/dbt/models/. The schema.yml file provides metadata for dbt models, including model dependencies, column definitions, and data quality tests. It utilizes macros likeget_dq_macro.sqlanddq_referentialcheck.sql(found under the macros/ directory) to enforce these validations.
As a result, dbt automatically generates a lineage graph based on the declared dependencies. This visual graph helps orchestrate model execution order—ensuring models like
mwaa_blog_customers.sqlrun before dependent models such asmwaa_blog_cards.sql, and identifies which models can execute in parallel to optimize the pipeline. - These relationships and checks are defined in the
- As a pre-step before running models, choose the trigger DAG button for create-audit-table to create audit table for storing run details for each model.

- Trigger the
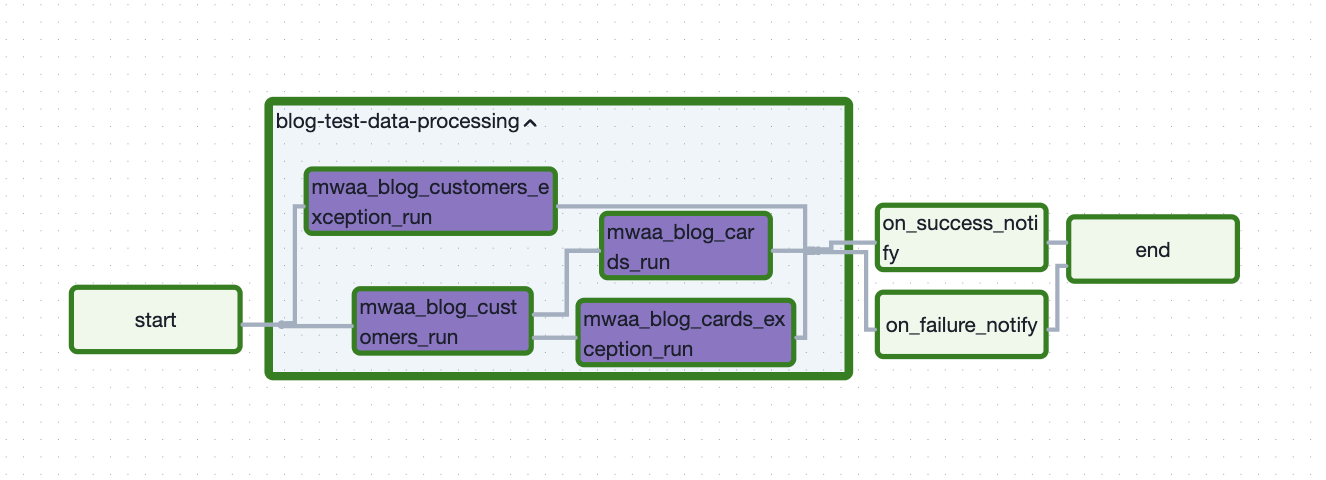
blog-test-data-processingDAG in the Airflow UI to start the Model run. - Choose
blog-test-data-processingto see the execution status. This DAG runs the models in order and creates Glue catalogued iceberg tables. The flow diagram of a DAG from Airflow UI can be found by choosing Graph after choosing DAG.


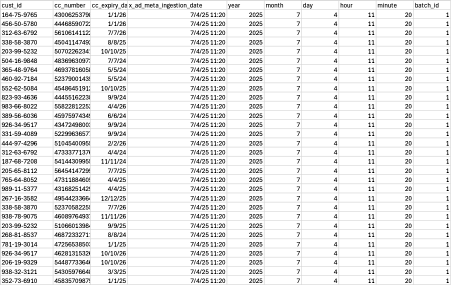
- The exception models puts the failed records under exception prefix in S3:
Records that failed are found in an added column, tests_failed, where all the data quality checks that failed for that particular row are added, separated by a pipe (‘|’). (For the
mwaa_blog_customers_exceptiontwo exception records are found in the table.) - The passed records are put under formatted prefix in S3.
- For each run, a run audit is captured in the audit table with execution details like model_nm, process_nm, execution_start_date, execution_end_date, execution_status, execution_failure_reason, rows_affected.
Find the data in S3 under the prefixbdb4834-formatted-bucket-<aws-account-id>-<region>/audit_control/ - Monitor the execution until the DAG completes, which can take up to 2-3 mins. The execution status of the DAG can be seen in the left panel after opening the DAG.

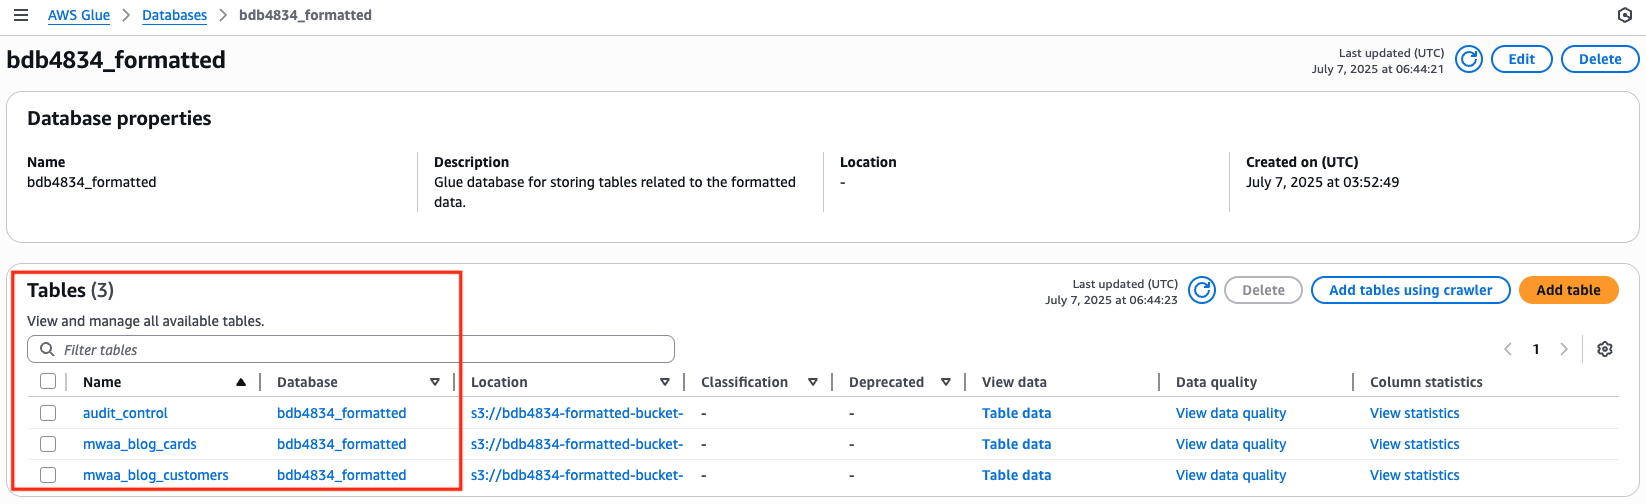
- Once the DAG has completed successfully, open the AWS Glue console and select Databases. Select the
bdb4834_formatteddatabase, which should create three tables, as shown in the following image.
Optionally, choose Table data to access Athena for data analysis.

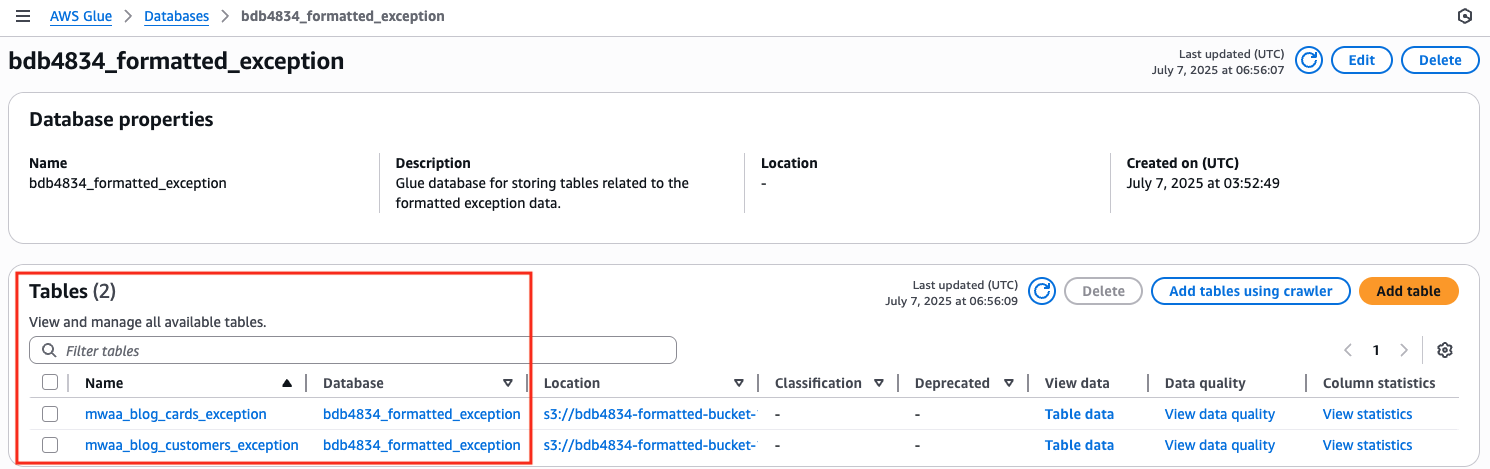
- Choose
bdb4834_formatted_exceptiondatabase from under Databases in AWS Glue console, which should create two tables as shown in the following image.
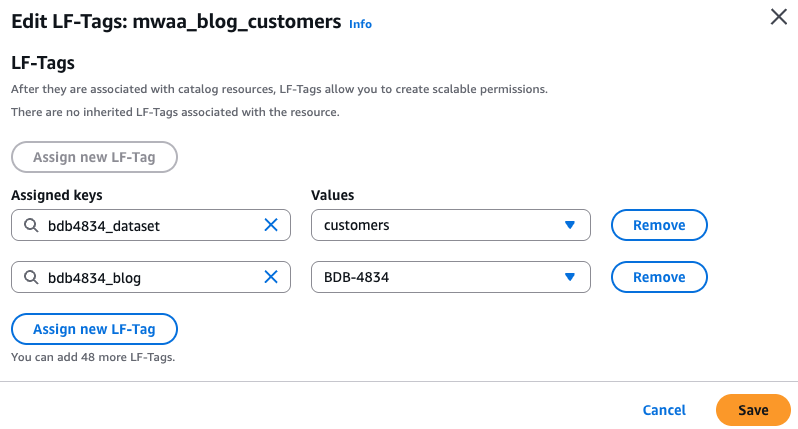
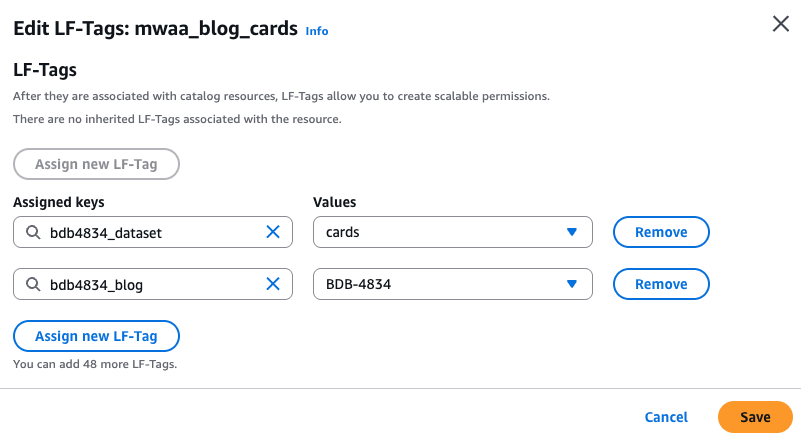
- Each model is assigned LF tags through the config block of model itself. Therefore, when the iceberg tables are created through dbt, LF tags are attached to the tables after the run completes.
Validate the LF tags attached to the tables by visiting the AWS Lake Formation console. In the left navigation pane, choose Tables and look for
mwaa_blog_customersormwaa_blog_cardstable underbdb4834_formatteddatabase. Select any table among the two and under Actions, choose Edit LF tags and the tags are attached, as shown in the following screen shot.


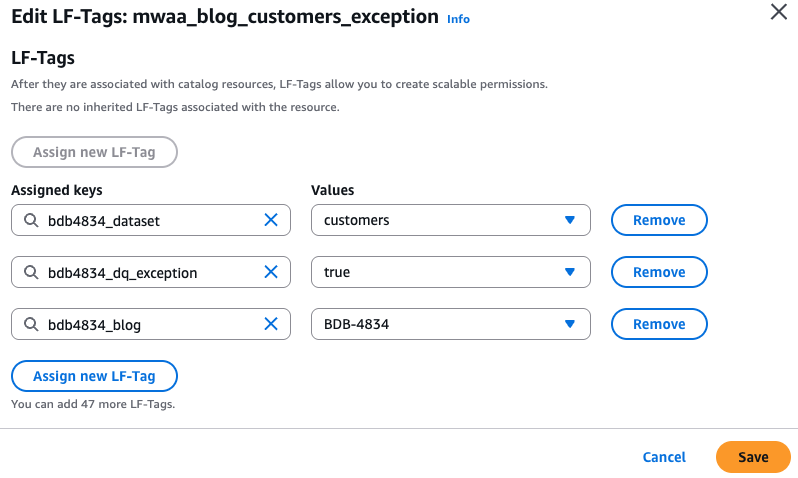
- Similarly, for the
bdb4834_formatted_exceptiondatabase, select any one of the exception tables under thebdb4834_formatted_exceptiondatabase and the LF tags are attached.

- Run SQL queries on the tables created by opening the Athena console and running Analytical queries on the tables created above.Sample SQL queries:


- The exception models puts the failed records under exception prefix in S3:




Governance using Lake Formation
In this section, we show how assigning Lake Formation permissions and creating LF tags is automated using the metadata file.Below is a metadata file structure, which is needed for reference when uploading the metadata file for Lake Formation in Airflow S3 bucket, inside the Lake Formation prefix.
Components of the metadata file
role_arn: The IAM role that the Lambda function assumes to perform operations.access_type: Specifies whether the action is to grant or revoke permissions (GRANT, REVOKE).lf_tags: Tags used for tag-based access control (TBAC) in Lake Formation.named_data_catalog: A list of databases and tables on which Lake Formation permissions or tags are applied to.table_permissions: Lake Formation-specific permissions (e.g., SELECT, DESCRIBE, ALTER, etc.).
Lambda function bdb4834-lf-tags-automation parses this JSON and grants the required LF tags to the role with given table permissions.
- To update the metadata file, download it from the MWAA bucket (lakeformation prefix)
- Add a JSON object with the metadata structure defined above, mentioning the IAM role ARN and the tags and tables to which access needs to be granted.
Example:Let’s assume below is how the metadata file initially looks like:Below is the json object that has to be added in the above metadata file:
So now, the final metadata file should look like:
- Upon uploading this file at the same location (
bdb4834-mwaa-bucket-<<ACCOUNT_NO>>-<<REGION>>/lakeformation/) in S3, thelf_tags_automationlambda is triggered to create LF tags if they don’t exist and then it assigns those tags to the IAM role ARN and also grants permission to the IAM role ARN usingnamed_data_catalogas defined.To verify the permissions, go to the Lake Formation console and choose Tables under Data Catalog and search for the table name.


To check LF-Tags, choose the table name and under the LF tags section, all the tags are found attached to this table.
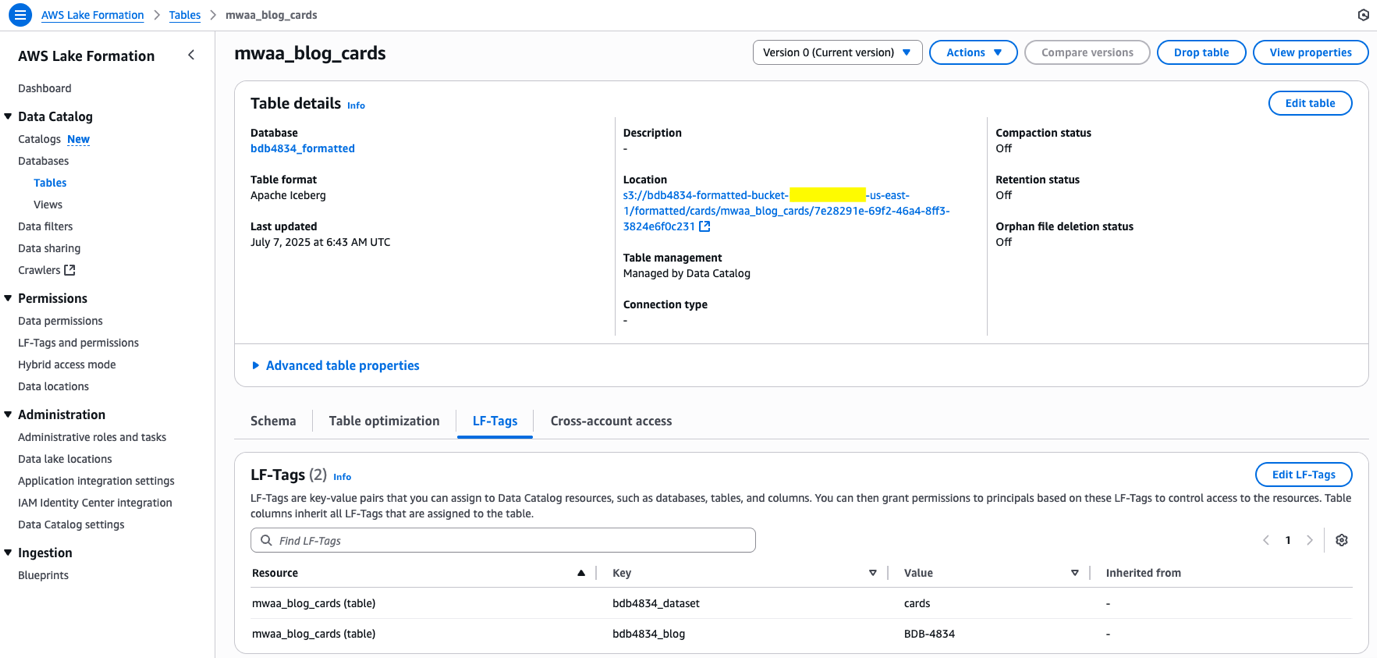
This metadata file used as a structured input to an AWS Lambda function automates the following to perform automated, consistent, and scalable data access governance across the AWS Lake Formation environments:
- Granting AWS Lake Formation (LF) permissions on Glue Data Catalog resources (like databases and tables).
- Creating Lake Formation Tags and Applying Lake Formation tags (LF-Tags) for tag-based access control (TBAC).
Explore more on dbt
Now that the deployment includes a bdb4834-published S3 bucket and a published Catalog database, robust dbt models can be built for data transformation and curation.
Here’s how to implement a complete dbt workflow:
- Start by developing models that follow this pattern:
- Read from the formatted tables in the staging area
- Apply business logic, joins, and aggregations
- Write clean, analysis-ready data to the published schema
- Tagging for automation: Use consistent dbt tags to enable automatic DAG generation. These tags trigger MWAA orchestration to automatically include new models in the execution pipeline.
- Adding new models: When working with new datasets, refer to existing models for guidance. Apply appropriate LF tags for data access control. The new LF tags can also now be used for permissions.
- Enable DAG execution: For new datasets, update the MWAA metadata file to include a new JSON entry. This step is necessary to generate a DAG that executes the new dbt models.
This approach ensures the dbt implementation scales systematically while maintaining automated orchestration and proper data governance.
Clean up
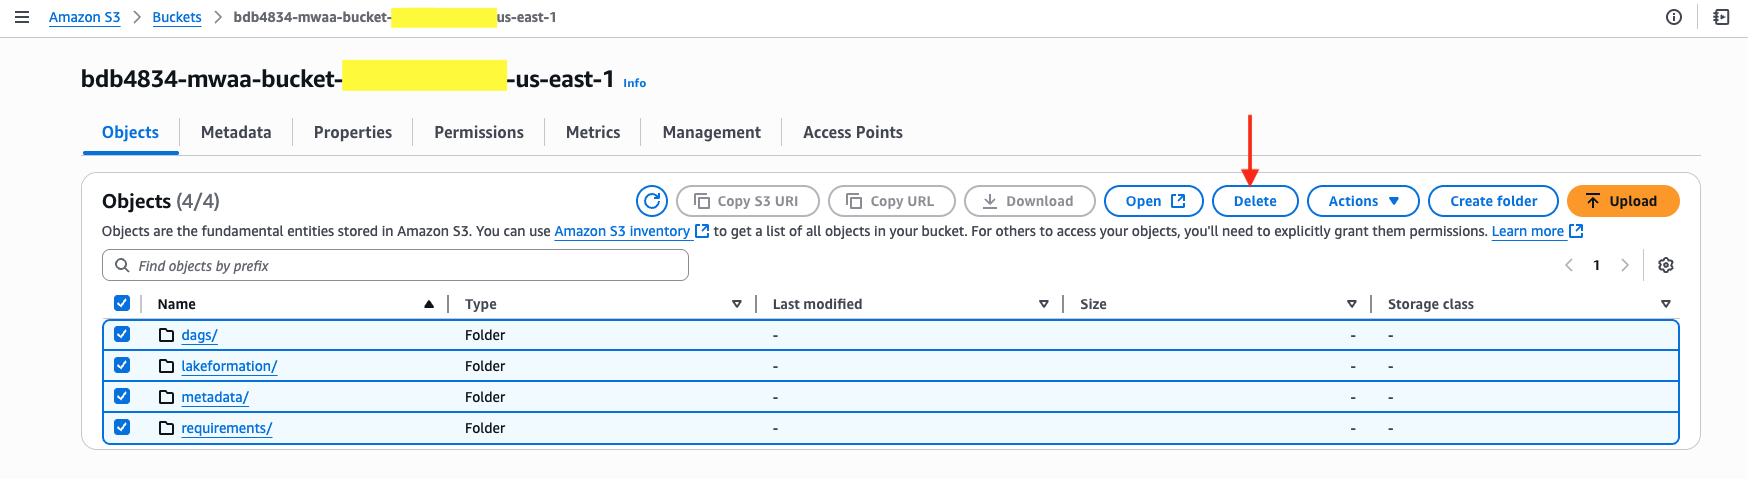
1. Open the S3 console and delete all objects from below buckets:
- bdb4834-raw-bucket-<aws-account-id>-<region>
- bdb4834-formatted -bucket-<aws-account-id>-<region>
- bdb4834-mwaa-bucket-<aws-account-id>-<region>
- bdb4834-published-bucket-<aws-account-id>-<region>
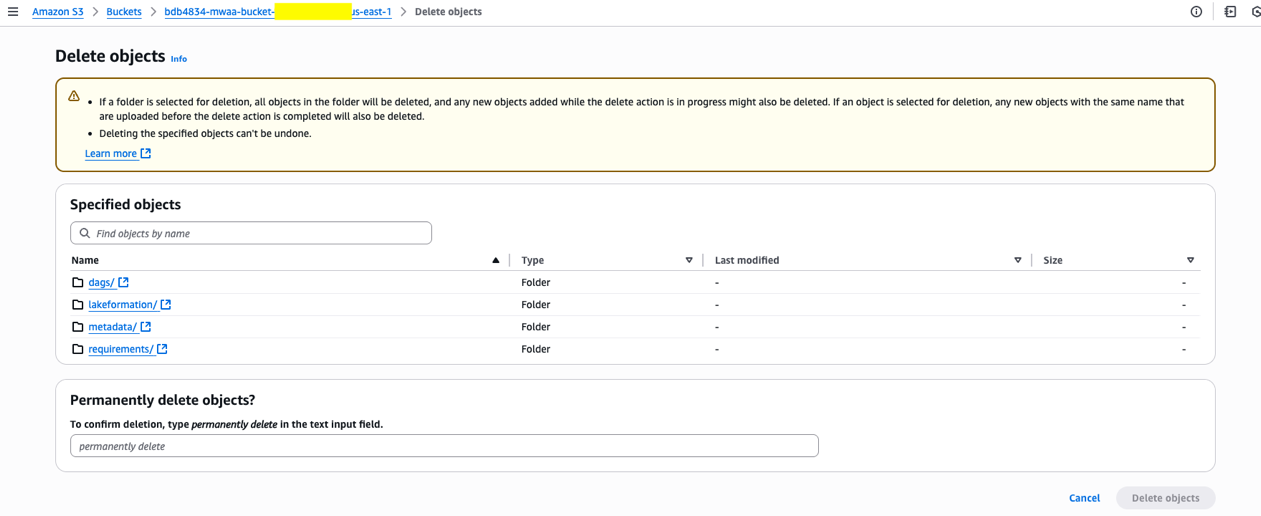
To delete all objects, choose the bucket name, select all objects and choose Delete.
After that, type ‘permanently delete’ in the text box and choose Delete Objects.
Do this for all three buckets mentioned above.
2. Go to the AWS Cloudformation console, choose you’re the stack name and select Delete. It may take approximately 40 mins for the deletion to complete.
Recommendations
When using dbt with MWAA, some typical challenges include worker resource exhaustion, dependency management issues, and in some rare cases, issues like DAGs disappearing and re-appearing when there are a large number of dynamic DAGs being created from a single python script.
To mitigate these issues, follow these best practices:
1. Scale the MWAA environment appropriately by upgrading the environment class as required.
2. Use custom requirements.txt and proper dbt adapter configuration to ensure consistent environments.
3. Set airflow configuration parameters to tune the performance of MWAA.
Conclusion
In this post, we explored the end-to-end setup of a governed data lake using MWAA and dbt which improved data quality, security, and compliance, leading to better decision-making and increased operational efficiency. We also covered how to build custom dbt frameworks for auditing and data quality, automate Lake Formation access control, and dynamically generate MWAA DAGs based on dbt tags. These capabilities enable a scalable, secure, and automated data lake architecture, streamlining data governance and orchestration.
For further exploring, refer to From data lakes to insights: dbt adapter for Amazon Athena now supported in dbt Cloud
About the authors
The David Frum Show: Could Nicolás Maduro be acquitted?
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/3vEHUJQeiGs