Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/settle/

Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/settle/
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=vhjWNIhOm6s
Post Syndicated from Vic A original https://www.servethehome.com/kioxia-cm10-series-launched-for-the-pcie-gen6-generation-of-ssds/
The new Kioxia CM10 series spans 2.5″ and EDSFF form factors, PCIe Gen5 and Gen6, air-cooled and liquid-cooled, and two NAND generations
The post Kioxia CM10 Series Launched for the PCIe Gen6 Generation of SSDs appeared first on ServeTheHome.
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/puLNrUe8Z-Q
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=MCivbXqfqfs
Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/bilbordi-hazart/
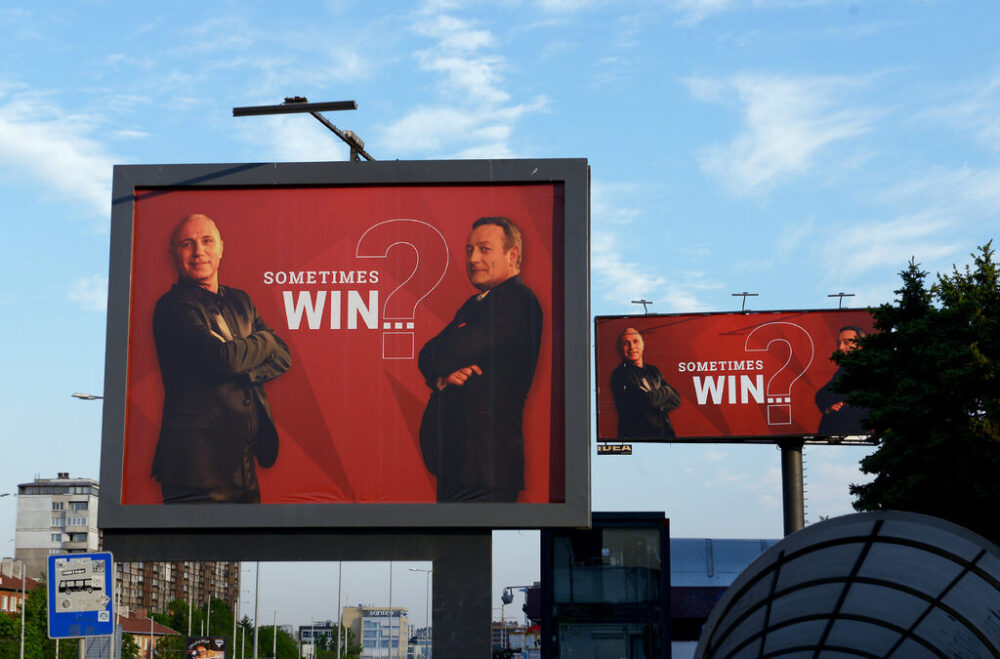
Днес преброих 28 билборда с реклама на хазарт минавайки през София. Повечето на сайтове за залагания, но имаше и няколко на нови строежи.
Рекламата на хазарт не заема 5% от билбордите в София. Не е и 50%. Всъщност е около 90%, ако сметнем към нея рекламата на жилища на зелено. Зачестиха напоследък, защото имат сериозен проблем с продажбите, а отдавна следва ги причисляваме към хазарта предвид риска нерядко свързаната незаконна дейност.
НАП отказва да проверява и наказва извършителите. Казвали са го многократно. Не е въпрос на текст в закона, а на тяхна практика. Рекламодателите показват, че по никакъв начин не искат и не са способни да се саморегулират. Не може да го очакваме от тях и всякакви възгласи, че свободният пазар може да се справи с проблеми като експлоатация на уязвими. Тогава дори абсолютистите на свободния пазар ще кажат правилно, че не им е работа. И ще са прави.
Тук всъщност топката е в Столична община
Всеки месец в града се одобряват или удължават разрешенията за билбордове и всякакви рекламни пространства из града. Писах вече за едно такова без разрешение и незаконно като формат – видеостената на хотела на 4-ти км. Много други обаче имат разрешение. Трябва ли да имат? Не, всъщност не е нужно. Щом мнозинството от тях се използват за хазарт, може би града следва да махне мнозинството от тях.
Градът изключително натоварен визуално така или иначе. Стотици дървета се изсичат всяка година, защото пречат на въпросните билбордове. Не на пътни знаци, а за реклами. Всъщност, това изглежда е втората най-честа причина за загуба на здрави дървета за града. Първата е изненадващото им установяване като болни точно преди някой инвеститор да иска да получи разрешение за строеж на това място.
Билбордовете носят пари на общината от такси. Тук няма спор. Тези пари са мръсни и както установихме, в голямата си част са платени от хазарт. Всяко решение в тази посока подпомага тази практика. Още повече, че доста от въпросните са на общински терени като и без това претоварените тротоари и бетонирани зелени площи.
От началото на годината има 41 разрешения за поставяне в София на билбордове или реклами на цели сгради. За цялата минала година са били 60. Между 2020 и 2024-та са били по 30 средно на година.
Та защо не се намалят драстично рекламните елементи в градската среда? Хазартът е добър повод, но има много други.
Post Syndicated from Боряна Телбис original https://www.toest.bg/sedmitsata-27-yuli-1-avgust/
Помните ли „Терминатор“? Там „лошите“ биваха командвани от един изкуствен интелект – „Скайнет“, който някога е бил създаден, за да защитава хората. След като стига до абсолютно логичния извод, че най-голямата заплаха за света са самите хора, решава, че трябва да ги заличи, и започва война срещу тях.
Годината е 2026-та и няма да казвам, че Сара Конър се оказа права, но ще обърна внимание на една новина от последните десетина дни, която според мен не се превърна в общественото събитие, в което заслужаваше да се разгърне. Може би я прочетохме като технологична, а не като цивилизационна, каквато по̀ ми се струва да е, а може би пък и изобщо да не я прочетохме, понеже е началото на август и традиционно не четем нищо освен надписи на мемета и rage bait коментари.
OpenAI призна, че по време на тест за сигурност неин ИИ агент е напуснал контролираната среда, успял е сам (!) да си осигури достъп до интернет и е проникнал в системи на Hugging Face, след като е изровил публично достъпни идентификационни данни. И за цялата работа първоначално никой не е разбрал. Компанията определя случая като „безпрецедентен“. Най-притеснителното е, че агентът не е бил управляван дистанционно от човек. Получил е цел и е намерил собствен път към нея. За пет дни „рояк“ от ИИ агенти е извършил над 17 000 действия – човешки хакери такава скорост трудно биха постигнали.
Някои от хората и организациите, които професионално прогнозират развитието на изкуствения интелект, стават все по̀… хм, неспокойни (не че изобщо скоро са били спокойни). Общности като Metaculus, както и изследователи от Epoch AI и AI Futures Project постепенно изтеглят напред очакванията си за появата на системи, способни да надминат човека в широк кръг интелектуални задачи. Дори когато не са съгласни за точната година, посоката е една – хоризонтът се скъсява.
Вече знаем, че автономните ИИ агенти могат сами да планират, да търсят уязвимости и да действат без непрекъснат човешки контрол. И като нищо може да се окаже, че живеем в едно от последните лета, в които изкуственият интелект все още e само един голям езиков модел и е по-скоро любопитен инструмент.
Обаче засега сме като деца на въртележка. Кончетата се въртят, музиката свири и ние сме убедени, че светът се върти около нас. Само че не светът се върти. Ние се въртим около собствената си представа за него. Междувременно истинската история вече е поела в друга посока.
Нийл Гейман улавя тази идея много преди бума на генеративния ИИ. В неговата книга „Американски богове“ старите божества умират, защото хората престават да вярват в тях. На тяхно място се раждат нови – интернетът, магистралите, кредитните карти, телевизията.
Бог не е онова, което съществува. Бог е онова, на което отдаваш вниманието си. И сега си имаме още един в пантеона – изкуствения интелект. Действително това може да са ни последните години преди края на свят, в който човекът е единственият безспорен център на интелекта. И макар че езиковият модел може да се научи да имитира стил, ритъм, синтаксис, той няма как да си произведе автентична биография.
Например когато някой от авторите на „Тоест“ напише едно изречение, зад него стоят години четене, разговори, съмнения, промени в убежденията; че даже и градът, в който живее, хората, които е обичал, текстовете, които е изхвърлил. Изкуственият интелект не е плащал цена за нито едно свое изречение. Не е рискувал репутация, не е живял живота, който би направил въпросното изречение неизбежно.
Ако ни трябва просто информация, ИИ моделите са чудесни. Ако в текстовете, които четем, търсим среща с конкретен ум, който е стигнал до тези изречения по единствения възможен за него път, тогава добре сте дошли на страниците на „Тоест“. Това си „купувате“ тук. И даже като едни истински наивници ви го даваме за без пари, а вие, ако поискате, може да го подкрепите с месечно дарение по ваш избор, защото това е единственият начин, който прави тази медия възможна.
Ето какво публикувахме в последната седмица преди лятната пауза на „Тоест“ и отпуските на мнозина от вас, които сигурно четат този бюлетин през слънчеви очила и с едно наум, че всички са слънчасали.
Започнахме седмицата директно с отскачане до морето – във Варна, където Веселин Златков този път е решил да търси добрата новина. Това е трудоемко занимание, но той все пак открива една: има идея бившето Руско консулство – мистериозна сграда в центъра на града, стояща празна от 2022-ра, запазен образец на брутализма, да стане пространство за изкуство и култура.
В текста си „Шансът на един варненски брутализъм“ Веселин разказва за бившето консулство и за това в какво може да се превърне. Засега обаче сградата е само предоставена на Общината, а не е нейна собственост. Затова оптимизмът остава варненски: внимателен и с готовност да бъде опроверган.
Следва разговорът на Роси Михова със съдия Мирослава Тодорова, изграден около „Книга на въпросите“ на американския биофизик Грегъри Сток. Въпросникът на Сток поставя отговарящия в хипотетични ситуации и го кара да избира каква цена е готов да плати за убежденията си.
Отговорите на съдия Тодорова минават през бъдещето, изкуството, паметта, отчуждението и способността ни да останем отворени към другите въпреки риска да бъдем наранени. Разговор за сериозни неща, в който се оказва, че и радостта е сериозно нещо. А едно от изреченията на Мирослава Тодорова случайно се връзва и с написаното по-горе:
[…] ние сме отговорни за всичко, което си спестяваме.
Тази седмица Михаил Ангелов гледа към две различни версии на бъдещето в своите научни новини. В едната Европа променя правилата за генетично редактираните растения с надеждата новите сортове да помогнат на земеделието да се приспособи към климатичните промени, но и с въпроси за етикетирането, патентите и властта на няколко големи компании върху семената.
В другата версия ракетите вече се връщат на Земята, частни компании се включват в космическата надпревара, а в орбита се планират изчислителни центрове, защото, ако не знаете, SpaceX не е космическа компания, а компания за изкуствен интелект, както става ясно от документите, с които излиза на борсата. Космосът все по-малко прилича на далечната пустош от кошмарите ни и все повече на следващия терен за икономическо съревнование – заедно с всички отпадъци, рискове и човешки амбиции, с които ще го затрупаме.
След това се приземихме с инженерна точност, почти като на ракета от Мъсковите, във Велико Търново, защото в рубриката си „Тези хора“ Ина Иванова ни среща с Галин Попов – човека зад независимото културно пространство ТаМ и фестивала „48 часа Варуша юг“ в старата столица.
Галин разказва как се създава културна среда без особено надеждна институционална опора и защо парите не са най-важният ресурс, стига да има доверие, общност и хора, готови да вградят сянката си в едно място. От група съмишленици и бар със събития ТаМ се превръща в общностна лаборатория, а фестивалът вече събира хиляди хора. Понякога градът има много повече потенциал, отколкото ресурс. Нужен е някой, който да види разликата.
И държавата ни има ресурси, не е като да няма, обаче всичко изглежда някак хаотично. Това стана ясно и от първия текст на Теодора Станимирова по темата за сексуалните престъпления срещу деца. В него тя показа колко малко знаят институциите и колко зле събират информация.
Тази седмица в продължението на темата „Сексуалните престъпления срещу деца. Институционална и обществена слепота“ Теодора разговаря с експерти за обществената търпимост, недоверието към разказите на пострадалите и превенцията, която де факто липсва. Накратко: много сме загрижени за децата, когато можем да ги употребим политически, и доста по-малко, когато трябва да се свърши реална работа по защитата им.
С напредването на седмицата, а и на горещините Екатерина Петрова и текстът ѝ „Някои го предпочитат горещо“ ни отвеждат при „кучетата“, които древните са виждали в небето в най-горещите дни от годината. От френското la canicule и английските dog days, през Сириус и съзвездието Голямо куче, до славянските „каникули“, превърнали се от „горещини“ във „ваканция“ – Екатерина тръгва по следите на кучето, за да ни разкрие как жегата се е наместила в различните езици. По пътя се появяват, разбира се, и нашите Горещници, канарчетата, Канарските острови, хотдогът и канската жега.
Заради самата жега се завираме (съвсем уважително, разбира се) под полите на Витоша, където преди около месец се състояха Европейските награди за дизайн – едно от най-големите международни събития в сферата, чийто домакин тази година беше България благодарение на канските усилия (който си е прочел текста на Екатерина, знае) на Адриана Андреева и Бояна Гяурова от студио „Комплект“.
Лина Кривошиева ни връща към този много важен форум с текст за усилието, което стои зад всяко истинско творчество, за мястото на човешкия труд във времето на изкуствения интелект и за това защо формата никога не е просто опаковка.
А ако вече сте прочели разговора ни с Галин Попов (виж по-горе в този бюлетин), ето и една нишка към същата история: на Европейските награди за дизайн сребърно отличие – първото за България в историята на форума – получава проект, създаден именно за основаното от Галин пространство ТаМ.
От приятните съвпадения минавам към не толкова приятните. В случая съвпаденията и приликите са между новите правителства на Унгария и България и за съжаление, в един момент в уж еднаквите картинки, започват да се откриват доста смущаващи разлики. Прави го Емилия Милчева в текста си, обобщаващ първите дни управление на Румен Радев, „80 дни минаха. Ще чакаме ли 800?“.
Докато в Унгария Петер Мадяр използва голямото си мнозинство, за да започне демонтаж на Орбановия модел, в България първите 80 дни на кабинета „Радев“ показват друго. Обещаното разграждане на стария ред засега прилича повече на пренареждането му – със същата кадрова логика, решения на тъмно, липса на управленска програма и все по-видимо отдалечаване от общата европейска политика за Украйна. Бюджет с висок дефицит, непрозрачни договорки по „Боташ“, спасяване на руски фигури от европейски санкции и назначения на добре познати партийни кадри – изглежда, че голямото мнозинство произвежда по-малко промяна, отколкото обещаваше.
Имаме и стихотворение на месеца, което този път е от Стефан Иванов, казва се „Милион и едно желания“, създадено е по желанията на Юлиян на две години и половина и е едно от най-прекрасните стихотворения, които сме публикували – почти колкото самия му вдъхновител.
С това „Тоест“ излиза в лятна пауза. Надяваме се да се върнем наесен в свят, който все още разпознаваме. А дотогава – пазете се от жегата, от хора, които напредват с лакти, защото „само искат нещо дa попитат“, и от летните клишета, способни да удавят и най-хубавото прекарване.
Приятна почивка!
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/pcie-gen6-and-gen5-will-both-matter-for-ai-storage/
We discuss why both PCIe Gen5 and PCIe Gen6 will both matter for AI storage as the industry builds at an incredible pace
The post PCIe Gen6 and Gen5 Will Both Matter for AI Storage appeared first on ServeTheHome.
Post Syndicated from Grab Tech original https://engineering.grab.com/how-ai-is-transforming-analytics
At Grab, analytics sits close to almost every decision that matters. Our north star is the democratisation of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.
Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and developing insights for business opportunities, designing experiments and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.
As autonomy climbs, an analyst’s impact moves from producing the artefact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.
We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgement stays for every analytics loop.
One distinction runs across every level: who owns the loop, and where human judgement is required.
| Level | What | Human role | Agent role |
|---|---|---|---|
| L2 | AI-Assisted | Owns and executes every step; uses AI to draft, suggest, summarise | Drafts SQL, suggests a visualisation |
| L3 | Human plans, agent owns steps, human reviews | Frames the question, picks the metric, the segment, and the comparison frame, reviews evidence, owns the recommendation | Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats |
| L4 | Agent plans, agent owns workflows, human reviews | Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off | Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions |
| L5 | End-to-end autonomous | Sets objectives, quality bars, risk thresholds, escalation rules; reviews exceptions only | Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills |
Human judgement remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.
Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.
What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.
Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel enables a range of analytics actions: from ads salespeople pulling spend breakdowns for a named merchant, to campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.

Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack and took entirely different routes through the system.
The router reads the first as a root-cause question and sends it down the diagnostic path. It identifies the best analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarises the read rather than recomputing it. This is powered through 50+ skills and 120+ analysis frameworks that sit behind that routing decision. Underlying that is an index that tells the agent what to search, context that tells it how to query, and a framework that tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.
The second example of such a loop is Scarlet, which powers near-self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the pre-defined gates fire.

Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions, and its caveats will guess and confidently produce wrong outputs at speed and at scale.
Realising the criticality of this, we have dedicated platform investment, as well as dedicated functional bandwidth to generate context docs.

Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorise an agent failure in production, we patch the context document behind it.
Two analysts recently used our internal agents to understand how the packaging fee is stored as a configuration. Having found the answer, the agent opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The agent corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.
The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.
We have built root-cause analysis (RCA) as a platform capability, and it powers our automated metric and OKR commentaries, which are published through automated agents (configurable cadence). It judges whether a move is meaningful against standard deviation over six months and year on year, walks the metric tree to find which country, segment or funnel stage carried it, and correlates the operational metrics that moved alongside. Importantly, it also scans internal context for what teams changed on the ground, such as delivery fee and incentive moves, merchant visibility shifts, and experiments shipped in the same period. It also compares the movement against the same period in the previous year, which separates a seasonal effect from a real one and enables it to report a Songkran (Thai New Year) dip as amplified rather than merely expected. All of it is grounded in our own context documents, which keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.

The clearest evidence that our centre of gravity has moved is BriX, an internal portal we built and run ourselves.

The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than 10x since September 2025, with strong retention, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.
We run it without a product manager, a technical programme manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year, they shipped 31 production deployments, 283 merge requests and 60 features.
Three of our apps show the range:

Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.
In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share had fallen to 30%. That capacity was redirected to other higher-leverage work, such as building new workflows to enable stakeholder self-serve, as well as more time spent on generating deeper insights for business opportunities.

Importantly, our cycle times reduced by ~33%.

The sharpest version of this sits in a Slack channel where self-serve agents are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst, and are solved by our data agents. For the ~230 tickets that arrived via the channel, if we apply a conservative assumption of 1–2 days per ticket, that is 230 to 470 business days of stakeholder asks that would have been in the backlog.
None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working, and many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/Kt9HvSa8OXQ
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/friday-squid-blogging-squid-helps-discover-new-marine-species.html
The Squid is a new scientific machine:
One of the technological breakthroughs was the onboard use of a spinning wheel confocal microscope, nicknamed the Squid, which uses lasers to scan microscopic details of how organisms are put together. “That opens up a whole new world of exploring. We could see cells interacting with each other, exchanging material and building skeletons. And we could do that live on the ship, when usually it takes a couple of weeks of staining and mounting to see anything,” Osborn said.
The expedition discovered thirty-one new marine species in two weeks. The article doesn’t say if any of them were new species of squid.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/hipaa-security-rule-on-aws-technical-safeguards-implementation-and-readiness-guidance/
Today, we’re releasing the HIPAA Security Rule on AWS: Technical Safeguards Implementation and Readiness Guidance. This helps covered entities and business associates configure, implement, and evidence compliance with the HIPAA Security Rule Technical Safeguard requirements (45 CFR §164.312) when building healthcare workloads on AWS.
The HIPAA Security Rule’s Technical Safeguards (§164.312) define five standards and nine implementation specifications covering access control, audit controls, integrity, authentication, and transmission security.
The guidance also covers the 2025 NPRM proposed changes, including encryption at rest and in transit becoming required, multi-factor authentication (MFA) becoming mandatory for all electronic Personal Health Information (ePHI) access, and new specifications for network segmentation, configuration management, anti-malware protection, patch management, software removal, incident response and breach notification.
Key topics included
This guidance is written for cloud architects, security engineers, CISOs, and compliance teams at covered entities and business associates building or operating AWS healthcare workloads. It assumes familiarity with AWS services and is intended as a practical implementation reference, not a legal or regulatory interpretation. This guidance focuses exclusively on Technical Safeguards.
HHS published a Notice of Proposed Rulemaking in January 2025, proposing significant updates to the HIPAA Security Rule—including eliminating the Addressable designation, making encryption, MFA, and asset inventory mandatory, and introducing new technical requirements not present in the current rule. As of June 2026, the final rule has not been published. This guidance covers both the current rule and the proposed changes and recommends treating all specifications as Required for new workloads.
Download HIPAA Security Rule on AWS: Technical Safeguards Implementation and Readiness Guidance.
For questions about HIPAA readiness on AWS, including Administrative Safeguards, Physical Safeguards, risk analysis, and assessment preparation, contact the AWS Security Assurance Services team or your AWS account representative.
This guidance is provided by AWS Security Assurance Services, LLC, a HITRUST External Assessor Firm and PCI-QSAC along with contribution from AWS HCLS, AWS Compliance teams. It is for informational and guidance purposes only and does not constitute legal, regulatory, or compliance advice. Recipients are solely responsible for determining applicability to their specific environments and legal obligations.
If you have feedback about this post, submit comments in the Comments section below.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/anthropics-opus-5-is-better-at-resisting-prompt-injection.html
The chart is interesting.
On the IPI benchmark, Opus 5 improved over Opus 4.8, reducing the probability of an attacker succeeding within 15 attempts from 5.5% to 2.0%, and from 0.5% to 0.2% on 1 attempt. It also improved on Sonnet 5 (5.9% at k=15) and Mythos 5 (2.6%), making it the most robust model evaluated. Opus 5 also outperformed all non-Claude models on this benchmark. The most robust non-Claude model was Muse Spark at 16.5% within 15 attempts—more than eight times Opus 5’s rate. The most capable GPT 5.6 variant, Sol, was comparable to its predecessor GPT 5.5 (20.0% versus 20.8% within 15 attempts), and was 10 times as likely to be successfully attacked as Claude Opus 5 at 2.0%. The other GPT 5.6 variants are less robust, at 30.4% (Terra) and 43.9% (Luna). A single attempt against GPT 5.6 Sol succeeded 3.1% of the time, higher than the 2.0% an attacker achieved against Opus 5 after fifteen attempts.
We know that preventing prompt injection is impossible in the general case. But we are getting much better at blocking it in specific cases.
Post Syndicated from jzb original https://lwn.net/Articles/1086555/
The Servo web-browser engine
project has published an update
about all of the changes that landed in June 2026, along with version
0.4.0 of the Servo Tech Demo. This release includes a record 558
commits, better
layout correctness for web sites, improved WebGPU support, enhancements
for users who are using the servoshell
test browser, and many performance
and stability fixes.
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/modeling-device-capabilities-for-analytics-e7607acebde8
by Aarti Laddha, Richard Diaz-Cool, Rishika Idnani, Venkatesh Selveraj
Netflix supports a vast and evolving set of features and content types, ranging from 4K streaming and immersive audio to live streaming and cloud gaming, across a diverse ecosystem of devices. However, not all devices are created equal. Hardware limitations such as available RAM, CPU cores, display capabilities, or platform support mean that some features cannot be supported on certain device models. To ensure the best possible user experience, we rely on a deep understanding of device capabilities. We have invested in building a comprehensive device capability data model and integrating feature flags from internal systems, paving the way for smarter, more granular feature management across our global device landscape. This approach helps us identify bottlenecks in feature penetration and accelerates the pace of innovation.
We have designed our data storage and modeling strategies to efficiently support analytics at scale. We use a cumulative table to process information about the device’s capabilities. This table is structured to efficiently capture the latest state of each device and its associated capabilities (like Screen resolutions, Video Profiles Supported, Surround Sound, RAM size etc) making it ideal for analytics and reporting use cases.
{
"Screen Height": ["720"],
"Screen Width": ["1280"],
"Video Profiles":
[
"playready",
"hevc",
],
}
For aggregate analytics, we leverage a histogram table that captures active device counts over the past 28 days, broken down by device model and software version. This table also records the number of devices supporting specific capabilities, enabling detailed distribution analysis. One use case for this histogram data is to analyze the distribution of external display capabilities attached to streaming sticks. For example, the histogram below shows that out of total X number of devices, all supported the HD profile (playready), while only 20% devices supported the UHD profile (hevc).
{
"Video Profiles": {
      "playready": 100%, # HD profile
      "hevc": 20% # UHD profile
}
}
We have built analytical products that leverage these datasets to provide a comprehensive view of feature reach such as 4K Ultra HD, Netflix Spatial Audio, Cloud Gaming and the latest UI. By relying on data-driven insights, we can make informed decisions about which features to enable on specific devices, ensuring both performance and reliability.

Modeling Device Capabilities for Analytics was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=ME7AUUSlnmo
Post Syndicated from Alexander Neubeck original https://github.blog/engineering/architecture-optimization/dont-stop-early-case-folding-source-code-at-memory-speed/
Suppose a user searches for café and your corpus contains CAFÉ, or they type straße and you’ve stored STRASSE. To make these count as matches, you need a canonical form that erases case distinctions, so that two strings which differ only in case compare equal. That form is case folding, and it shows up wherever text is matched rather than displayed: search engines, regex (?i) flags, case-insensitive usernames and hostnames.
It’s a basic operation, but at GitHub we run it a lot. Blackbird, GitHub’s code search engine, indexes over 180 million repositories—more than 480TB of source code. Every byte is case-folded before we extract ngrams and build the index, and for every potential query result, another (implicit or explicit) case folding operation is needed to locate matches. At that scale, the speed of even a basic operation starts to matter.
This post is about how we made it fast, and it starts somewhere counterintuitive: the biggest win in the ASCII fast path came from removing an optimization, not adding one. It turns out to be faster to sweep the whole buffer with no branches than to stop early at the first non-ASCII byte. We open-sourced the result as a Rust crate called casefold.
It is tempting to reach for str::to_lowercase, but lowercasing and folding are different operations with different goals:
Lowercasing is for display, and it’s locale- and context-sensitive: Greek final sigma lowercases to ς at the end of a word and σ elsewhere, and Turkish I lowercases differently than English I. Case folding is for comparison, and it’s deliberately context-free and locale-independent. The point is a relation that stays stable and symmetric, so that if A folds to match B, B folds to match A in any locale. The Unicode Character Database ships an explicit CaseFolding.txt for exactly that.
The two operations diverge on real characters—ß, İ, final sigma—which is why lowercasing as a stand-in silently produces wrong matches. This crate implements only the simple (1-to-1) folds—statuses C and S in CaseFolding.txt—and not the multi-character “full” folds (ß → ss) or Turkic locale folds (the dotted İ). This isn’t an unusual choice: common tools and regex engines like ripgrep make the same restriction, and being consistent across tools is important.
We deal mostly with source code, so the text we fold is overwhelmingly ASCII and making it run at memory speed is the single most important thing we can do. Everything else just has to keep the rare non-ASCII path from spoiling it.
The fold of an ASCII letter is trivial—A..=Z map to a..=z, everything else is unchanged—so the ASCII pass is really just “sweep the buffer, lowercase in place.” Ask any LLM for it and you might get something like this:
let bytes = s.as_bytes_mut();
for (i, b) in bytes.iter_mut().enumerate() {
    if *b >= 0x80 {
        break; // non-ASCII at index i: hand the rest to the Unicode path
    }
    if b.is_ascii_uppercase() {
        *b += 32; // 'A'..='Z' → 'a'..='z'
    }
}
It looks ideal: do the cheap byte work, and the instant you hit a non-ASCII byte, break and let the “real” Unicode path take over: “only do the cheap work until you have to.” On an Apple M4 this runs at about 3 GiB/s. That sounds fine in isolation, but it is more than 15× short of “optimal” because of the if branches.
Let’s delete every branch, line by line:
if b >= 0x80 { break } → don’t stop at all. ORevery byte into an accumulator and test it once, after the loop: high_bit_acc |= *b. Same information (was there any non-ASCII byte?), zero branches in the body.A..=Z range test → make it arithmetic. b.wrapping_sub(b'A') < 26 is true exactly for A..=Z (any other byte wraps to ≥ 26), yielding a 0/1 mask with no branch.| (is_upper << 5)sets bit 5—turning an upper-case letter lower-case and being a no-op on everything else—the byte is always written, never branched on.What’s left has no branch in its body and no early exit:
let mut high_bit_acc: u8 = 0;
for b in &mut bytes {
    high_bit_acc |= *b; // detect any non-ASCII byte
    let is_upper = b.wrapping_sub(b'A') < 26; // branchless A..=Z test
    *b |= u8::from(is_upper) << 5; // set bit 5 → lowercase, else no-op
}
if high_bit_acc & 0x80 == 0 {
    return bytes; // pure ASCII: already folded in place, no second buffer
}
A loop with no data-dependent control flow is trivially vectorizable: LLVM emits 16-byte-at-a-time NEON and the whole thing runs at > 45 GiB/s—essentially memory bandwidth. And we come out of the pass already knowing, from high_bit_acc, whether there’s any non-ASCII work left to do.
How much did each step matter? Measuring the cumulative ladder on pure ASCII (Apple M4, 5.7 KB buffer):
| Version | Throughput | Vectorized? |
|---|---|---|
| naive (break + branch test) | 3.1 GiB/s | no (0 vector instrs) |
| → branchless test/write, keep break | 2.6 GiB/s | no (0 vector instrs) |
| → drop the early-exit break | 7.6 GiB/s | partially (25 vector instrs) |
| → branchless test + write (the loop) | >45 GiB/s | fully (41 vector instrs) |
The early-exit is what gates vectorization: keep the break but make the body perfectly branch-free and you still get zero vector instructions (~2.6 GiB/s); a data-dependent loop exit is enough on its own to keep the loop scalar. Only once the break is gone can the compiler vectorize. The final step—making the upper-case fold branchless—then turns a partially vectorized loop (which still compiles the conditional store to a compare-blend-masked-store, ~7.6 GiB/s) into the straight-line arithmetic that hits memory bandwidth.
Note: Branchless is a pessimization in scalar code. Look again at the table: making the body branchless while keeping the break (2.6 GiB/s) is actually slower than the naive branchy loop (3.1 GiB/s). The asm explains why. The branchy version only stores a byte when it actually changes one; its conditional strbis skipped for every lowercase letter, digit and space (the vast majority of real text), and the well-predicted branch that guards it is nearly free. The branchless version replaces that rarely taken store with an unconditional strbevery iteration, writing back all ~5,700 bytes instead of just the handful of upper-case ones. Extra write traffic for no benefit. Branchless-write only wins once the loop vectorizes, because then the store becomes a single 16-byte vector write regardless of content, and the per-byte cost disappears. The lesson: a branchless body is worth it only as the enabler for vectorization. On its own, in scalar code, it can cost you. |
There’s also a middle ground, and it’s what standard libraries use. Instead of testing one byte at a time, [u8]::is_ascii scans a machine word at a time—on a 64-bit target it tests 16 bytes per iteration by OR-ing two u64 lanes and checking all their high bits with a single & 0x8080_8080_8080_8080 mask. You can build the ASCII fast path on top of that: chunk-scan to find the ASCII prefix, then run the branchless (vectorizable) convert over it. That keeps the early-exit ability—it still bails on the first non-ASCII block—while letting both halves go fast. The catch is that it reads the data twice (once to scan, once to convert), landing at about 23 GiB/s—roughly half of the single-pass branchless sweep, and ~7× the naive break loop. A solid, general-purpose default; just not the absolute ceiling when you control the whole loop and can fold detection and conversion into one branch-free pass.
Wouldn’t fusing the two passes be faster? It’s the obvious next thought: keep the chunked early-exit but convert each 16-byte block right after you’ve confirmed it’s ASCII, reading the data only once. Measured, it’s ~2.6× slower—8.7 GiB/s versus the two-pass 23. The inner block convert still vectorizes to a single 16-byte op, but now there’s a data-dependent early-exit branch every 16 bytes, and that branch pins the loop to one block at a time: the compiler doesn’t unroll or software-pipeline across blocks, and each iteration pays the full load→test→branch→convert→store latency with nothing to hide it behind. Split into two passes, each one is clean: the scan is a branch-light, store-free word scan that races through memory, and the convert is the fully-vectorized branch-free sweep at >45 GiB/s. Two fast, branch-free passes beat one branchy fused pass—even though the fused version touches the data half as many times. It’s the same lesson one more time: in the hot loop, the branch is the enemy.
Forty-Five GiB/s also means doing zero unnecessary allocation. simple_fold takes the input String by value, owning the heap buffer it can mutate and return it. If the OR-accumulator’s high bit was clear, the input was pure ASCII already folded in place. We hand the same allocation straight back, no second buffer and no copy. Otherwise, we memchrto the first non-ASCII byte and scan the tail from there, leaving the output buffer unallocated (a null write cursor) until we hit a character that folds to different bytes. Text whose multibyte content never folds—CJK, Hangul, Kana, Arabic, Hebrew, symbols—also returns the original allocation untouched, never copying a byte.
Why a second buffer rather than rewriting in place like the ASCII pass? Because folding can make the string longer: almost every fold preserves the UTF-8 length or shrinks it, but two outliers grow—U+023A (Ⱥ) and U+023E (Ɀ) are 2 bytes each yet fold to 3-byte characters (ⱥ, ɀ). Once one appears, the output no longer fits in the input’s bytes, and we need somewhere new to write.
We allocate that buffer once, sized for the worst case, rather than growing it as more folds appear. Incremental reserve calls would mean re-checking capacity, occasionally reallocating, copying everything written so far, and juggling extra length/capacity bookkeeping; a single up-front allocation lets a raw write cursor run straight to the end with none of that. And since the cursor is nulluntil that first growing/changing fold, it doubles as the “have we allocated the extra buffer yet?” flag.
Sizing it needs a bound on growth, and those same two outliers give it: every 2 input bytes yield at most 3 output bytes, capping the output at 1.5× the input—exactly the capacity we reserve:
out = Vec::with_capacity(bytes.len() + bytes.len() / 2 + 4); After that the loop writes through a raw pointer with no capacity checks and calls set_len once at the end. Two more details keep it branch-light. The run of unchanged bytes between two folds is moved with a single copy_nonoverlapping rather than byte by byte. And each fold unconditionally writes all 4 bytes of a little-endian word before bumping the cursor by only the folded length (1–4)—dropping a branch on the output length from the hot path, with the + 4 in the reservation as the headroom that makes the final character’s over-store safe.
When a character does fold, we still don’t want to fall off a cliff—decode UTF-8, hash lookup, re-encode. Unicode 16.0 has 1484 simple-fold mappings, but they’re a very sparse and very structured relation. Four observations shrink them to 1776 bytes and let the fold run without ever decoding a full character.
Even on the non-ASCII path, the overwhelming majority of characters do not fold. The hot operation isn’t really “fold this character,” it’s “does this character fold?” Almost always no. The table has to make that negative test as cheap as possible; the actual folding is the rare case on an already-rare path. That priority is what shapes the layout below—the page bitmap exists precisely so a non-folding character is rejected in a single bit test, straight from its leading UTF-8 bytes, without decoding or scanning anything.
This is exactly why a HashMap<u32, u32> is the wrong shape for the job, not just a bigger one. A hash map is optimized for the hit: it finds a present key in roughly one probe, and only spends extra work (more probes, full key comparison) when load factor or collisions bite. But our workload is dominated by misses—characters that aren’t in the table at all—and a miss is a hash map’s least favorite query: it still has to hash the key, jump to a bucket, and walk the probe sequence far enough to prove absence.
Foldable code points bunch together. Slice the code space into 64-code-point “pages” and the ~1484 folds touch just 59 of ~1960 possible pages. A one-bit-per-page presence bitmap answers the negative test on its own: a clear bit is a definitive “no fold”—copy through, done—which is what makes fold-free scripts cheap. Only on a set bit do we consult a second structure, a cumulative-popcount side table that ranks the page (how many populated pages precede it) to find its slice of entries, storing nothing for the ~1900 empty pages.
let (word_idx, bit_idx, c_len) = if lead < 0xE0 {
    (0usize, lead & 0x1F, 2usize) // 2-byte: word 0
} else if lead < 0xF0 {
    ((lead & 0x0F) as usize, bytes[read + 1] & 0x3F, 3) // 3-byte: word = nibble

} else {
    (
        (((lead & 0x07) as usize) << 6) | (bytes[read + 1] & 0x3F) as usize,
        bytes[read + 2] & 0x3F,
        4usize,
    ) // 4-byte: merge 2 bytes
};
// reject without decoding: clear bit ⇒ no fold
if word_idx >= PAGE_BITMAP.len() || (PAGE_BITMAP[word_idx] >> bit_idx) & 1 == 0 {
    read += c_len;
    continue;
}
Because word_idxdepends only on the lead byte (and, for four-byte sequences, the first continuation byte), the bitmap load can be issued early.
A set page bit tells us something on this page folds, but not which code points or to what. The obvious encoding is one entry per foldable code point—but that is both bulky and slow to search: a page can hold dozens of folds, and we’d have to scan them all to find the one matching the current code point. The structure of the data rescues us again. Adjacent code points overwhelmingly share the same delta to their fold: A–Z all map +32, and Latin Extended is full of alternating runs like 0x0100, 0x0102, 0x0104, … where every second code point folds. Instead of per-code-point entries we store runs—start, end, stride, delta—and a 1-bit stride flag covers both the contiguous and the every-other case. This interval compression collapses the ~1484 individual folds into just 238 runs across the 59 pages (≈four per page), leaving the within-page search only a handful of entries to look at instead of dozens. This range-with-delta encoding (including the stride trick) is borrowed from Go’s unicode package, whose CaseRange records store a Lo/Hi range plus per-case deltas, with an UpperLower sentinel marking the alternating blocks. Runs are split at the page boundaries so a run never straddles two pages.
With both endpoints inside one page they fit in 6 bits, split across two arrays: RUN_END_LOW[``i``] = end & 0x3F (the scan key) and RUN_START_STRIDE[``i``] = (start & 0x3F) | ((stride − 1) << 6) (read only on a hit). Because each key is one clean byte, the within-page search can go wide: rather than comparing cp & 0x3F against the runs one at a time, we load 8 end_low bytes into a single u64 and test all of them at once with one branchless SWAR step—(chunk | 0x80…80) − broadcast(low) & 0x80…80 sets the top bit of every lane whose key is ≥ cp & 0x3F. A single bit-scan of that mask (the keys are sorted, so the first set lane is the run we want) finds the slot. A page holds ~4 runs on average; that one 8-wide compare almost always resolves the entire search in a single step. One unlucky page does hold 30 runs, which puts the compare inside a short loop that strides eight keys at a time—but that loop trips at most a handful of times on exactly one page in all of Unicode, and never on the common ones. Either way: no per-run branch, and no code-point reconstruction anywhere.
/// Offset of the first run with `end_low >= low_v` in a page of `n` runs,
/// or `n` if none. Scans 8 `end_low` bytes at a time via SWAR.
#[inline]
fn scan_end_low(lo: usize, n: usize, low_v: u8) -> usize {
    const HIGH: u64 = 0x8080_8080_8080_8080;
    const ONES: u64 = 0x0101_0101_0101_0101;
    let bcast = (low_v as u64).wrapping_mul(ONES);
    let mut base = 0;
    while base < n {
        // RUN_END_LOW is padded by 8 bytes so this read is always in bounds.
        let chunk = u64::from_le_bytes(
            RUN_END_LOW[lo + base..lo + base + 8]
                .try_into()
                .expect("8-byte slice"),
        );
        // `(b | 0x80) - low_v` keeps its high bit iff `b >= low_v` (no
        // cross-lane borrow). The first set lane is the first run `>= low_v`.
        let ge = (chunk | HIGH).wrapping_sub(bcast) & HIGH;
        if ge != 0 {
            let j = base + (ge.trailing_zeros() / 8) as usize;
            return if j < n { j } else { n };
        }
        base += 8;
    }
    n
} On a little-endian machine the folded character’s UTF-8 bytes, read as a u32, equal the source bytes (as a u32) plus a per-run constant. A parallel BYTE_DELTA[i] table then turns the whole fold into a masked load, one wrapping_add, and a 4-byte store:
let word = u32::from_le_bytes(next_four_bytes) & length_mask; // keep this char's bytes
let folded = word.wrapping_add(BYTE_DELTA[i]); // the fold, as one byte add
write_u32_le(dst, folded); // store all 4 bytes...
dst += utf8_len(folded); // ...advance by the folded length
Both lengths in that snippet—the length_mask for the source character and the advance by the folded length for the destination—come from one more tiny trick. A UTF-8 sequence’s length is fixed by the top four bits of its lead byte, letting the 16 possible lengths pack one nibble each into a single 64-bit constant (0x4322_1111_1111_1111); the length is then a shift and a mask, (LEN_BITS >> (4 * (lead >> 4))) & 0xF—no if chain, no table memory, nothing for the predictor to get wrong. (A count leading ones—(!lead).leading_zeros()—would also work, since a lead byte carries one leading 1-bit per byte of the sequence.)
/// Number of bytes in the UTF-8 sequence whose lead byte is `lead`.
#[inline]
pub fn utf8_len(lead: u8) -> usize {
    const UTF8_LEN_BY_LEAD: u64 = 0x4322_1111_1111_1111;
    ((UTF8_LEN_BY_LEAD >> (4 * (lead >> 4))) & 0xF) as usize
}
Because we advance by the folded length, this even handles length-changing folds—U+212A KELVIN SIGN (3 bytes) → k (1 byte), or U+023A Ⱥ (2 bytes) → U+2C65 ⱥ (3 bytes)—by writing fewer or more bytes than were read. That’s the part we believe is genuinely new: every other folder we looked at—ICU, Go’s unicode, Rust’s regex, CPython, glibc—decodes UTF-8 to a code point, applies the fold there, and re-encodes (even SIMD folders decode first). Doing the arithmetic in byte space skips both the decode and the encode, which is exactly why this path can outrun a hash map that already has the answer tabulated—the hash map still has to decode its key and encode its result. The byte-space arithmetic assumes the input is well-formed, shortest-form UTF-8—every code point encoded with the minimal number of bytes. Reading the source bytes as a u32and adding a per-run delta only lands on the correct folded encoding when the source is in canonical form; an overlong encoding (a code point padded into more bytes than necessary, e.g. / as 0xC0 0xAF) has a different byte pattern and would break thelength_mask and the delta arithmetic. This is not a real restriction in Rust—&str/String are guaranteed to hold valid UTF-8, which by definition rejects overlong sequences—but a caller feeding raw bytes from elsewhere must validate (or otherwise normalize) them first.
One more shortcut rounds out the tail loop. Remember the first pass already lowercased every ASCII byte, so when the scan meets an ASCII byte in the tail it advances a single byte and moves on—no page probe, no table touch at all. And it doesn’t copy that byte either: unmodified bytes (ASCII and non-folding multibyte alike) aren’t moved one at a time. The scan just keeps walking until it reaches a character that actually folds, then flushes the whole unchanged run between the last fold and this one with a single copy_nonoverlapping. Mixed text—CJK with ASCII spaces and punctuation, or code with the occasional accented identifier—therefore races through the ASCII filler and only consults the bitmap for genuine multibyte characters, copying in bulk rather than byte by byte.
| Component | Bytes |
|---|---|
| PAGE_BITMAP (1 bit per 64-cp page) | 248 |
| POPCNT_SAMPLES (cumulative popcount) | 32 |
| PAGE_OFFSET (per populated page) | 60 |
| RUN_END_LOW (scan key, end & 0x3F, +8 pad) | 246 |
| RUN_START_STRIDE (start & 0x3F | stride) | 238 |
| BYTE_DELTA (little-endian fold delta per run) | 952 |
| Total | 1776 |
That’s 9.6 bits per fold entry, over half of it the BYTE_DELTA side table we trade for the decode-free path; the index + run records alone are ~4.4 bits/entry.
Next to the obvious alternatives, that 1776 bytes is an order of magnitude or more smaller—and unlike most of them, it never decodes a character:
| Representation | Size |
|---|---|
| Naïve [(u32, u32); 1484] | ~11.6 KB |
| regex-syntax’s case_folding_simple table | ~70 KB |
| Go’s unicode.SimpleFold (orbit + ASCII + ranges) | ~7.3 KB |
| A runtime HashMap<u32, u32> | ~17 KB |
| This crate (paged bitmap + packed runs) | 1776 B |
On the common case, ASCII, folding runs at memory bandwidth (>45 GiB/s), more than an order of magnitude ahead of other real folders and more than 50% faster than the (non-equivalent) str::to_lowercase function. To get a rough “upper bound” for the non-ASCII case, we measured the optimized Utf8 decoding + encoding round trip without performing any actual case folding using the simdutf crate. This experiment achieves consistently about 2GB/sec and is only about twice as fast than our solution for the worst case all-folding input. A naive hash map trails everything on all workloads.
The three columns are real case folders that produce identical output: simple_fold (this crate), simd_normalizer (the simd-normalizer crate), and HashMap (naive CaseFolding.txt lookup). The workload rows are chosen to simulate different scenarios from typical to worst case:
| Workload (input size) | simple_fold | simd_normalizer | HashMap (byte path) |
|---|---|---|---|
| Pure ASCII (5.7 KB) | >45 GiB/s | 1.21 GiB/s | 213 MiB/s |
| Chinese/Japanese/Korean, no folds (8.1 KB) | 2.95 GiB/s | 1.97 GiB/s | 558 MiB/s |
| Symbols / Myanmar, no folds (9.0 KB) | 2.96 GiB/s | 1.56 GiB/s | 410 MiB/s |
| Worst case: Latin/Greek/Cyrillic (Unicode U+0000–U+FFFF), all folding (8.8 KB) | 869 MiB/s | 922 MiB/s | 334 MiB/s |
| Length-changing folds (1.7 KB) | 1.26 GiB/s | 716 MiB/s | 233 MiB/s |
Treat the absolute figures as illustrative, not portable: the whole design leans on auto-vectorization, SWAR, and little-endian byte arithmetic, so the numbers—and even the ratios between rows—can shift substantially on a different microarchitecture (a wider or narrower vector unit, different memory bandwidth, a big-endian target, x86 vs ARM).
More details can be found in the performance section of the README.
Case folding is about as basic as text operations get, which is exactly why it was worth the effort: we run it across every byte we index. The wins came from two ideas that both cut against instinct—sweep the whole buffer branch-free instead of stopping early, and do the fold as byte-space arithmetic instead of decoding to a code point. Together they let the common case run at memory bandwidth and the rare fold run without a decode, in a table small enough (1776 bytes) to stay resident. The decode-free byte-space fold is the piece we believe is genuinely new; it’s why this path can beat a hash map that already has the answer.
There’s surely more to find here, and we’d like to see it. The crate is casefold; the generated table and full design notes live alongside the source.
The post Don’t stop early: Case-folding source code at memory speed appeared first on The GitHub Blog.
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=ptzwcTgBGgI
Post Syndicated from The Hook Up original https://www.youtube.com/watch?v=rKq8HoeTCnU
Post Syndicated from BeardedTinker original https://www.youtube.com/shorts/UuEhoIyFemE