Historically, traffic graphs on Cloudflare Radar have displayed two metrics: total traffic and HTTP traffic. These graphs show normalized traffic volumes measured in bytes, derived from aggregated NetFlow data. (NetFlow is a protocol used to collect metadata about IP traffic flows traversing network devices.) Today, we’re adding an additional metric that reflects the number of HTTP requests, normalized over the same time period. By comparing bytes with requests, readers can gain additional insights into traffic patterns and user behavior. Below, we review how this new data has been incorporated into Radar, and explore HTTP request traffic in more detail.
Note that while we refer to “HTTP request traffic” in this post and on Radar, the term encompasses requests made in the clear over HTTP and over encrypted connections using HTTPS – the latter accounts for ~95% of all requests to Cloudflare during July 2024.
New and updated graphs
Graphs including HTTP request-based traffic data have been added to the Overview and Traffic sections on Cloudflare Radar. On the Overview page, the “Traffic trends” graph now includes a drop-down selector at the upper right, where you can choose between “Total & HTTP bytes” and “HTTP requests & bytes”. We explore the distinction between these further in the following sections.
The default “Total & HTTP bytes” selection displays a time series graph, showing total bytes and HTTP bytes traffic over time, as Radar has done for several years now.
Selecting “HTTP requests & bytes” from the dropdown switches the view to a time series graph that HTTP requests traffic and HTTP bytes traffic over time. In both graphs, users can click on a metric in the legend to deselect it and remove it from the graph. These (de)selections are maintained when a user chooses to download or save a graph.
In addition, we’ve added a “Protocols” summary next to the graph that shows the share of bytes over the selected time period that HTTP accounts for, and the remaining aggregate share associated with the protocols used by other non-HTTP Cloudflare services (such as DNS, WARP, etc.). For most locations or ASNs, HTTP traffic will comprise the majority share of bytes-based traffic.
On Radar’s Traffic page, we have added the HTTP requests metric to the “Traffic volume” graph at the top of the page, allowing you to see how request volume has changed during the selected time period as compared to the previous period, in addition to the changes in the bytes-based metrics.
A new standalone request-based “HTTP traffic” graph was also added to the Traffic page, just below the bytes-based “Traffic trends” graph. This new graph shows normalized HTTP request traffic volume across the selected time period, and by default, also compares it with the previous time period.
Similar to other Radar graphs, these new HTTP request-based graphs can also be downloaded, copied to the clipboard, or embedded in other websites – just click on the share icon.
As always, the underlying data is also available through the Radar API. The “HTTP requests Time Series” API endpoint returns normalized HTTP request time series data across the specified time period for the requested location or autonomous system (ASN).
What is HTTP request traffic?
An HTTP GET request is a message sent from a client (such as your web browser) to a web server (such as one operated by Cloudflare), asking for a particular resource (file). In addition to returning the requested resource, which could range from a single-pixel GIF accounting for just a few bytes, to an API call that returns a few kilobytes of data, to a multi-gigabyte software package, the Web server also returns a set of headers, which can include information about the content type, the last time the resource was modified, cookie information, cacheability, and more. While GET requests account for the overwhelming majority of HTTP request traffic, such traffic also includes other HTTP request methods including HEAD, POST, PUT, and more.
Cloudflare temporarily logs HTTP requests received by our network, including associated header information and “metadata” about the request, such as the bot score computed for the request and the associated cache status. Request logs for a customer’s web properties are available for them to download, and after processing and analysis, this data is also presented in the Analytics section of the Cloudflare dashboard. The HTTP request data now available on Radar is based on a sample of this log data, aggregated across Cloudflare’s global customer base.
The value of request-based traffic insights
Cloudflare Radar already has HTTP data, so why add more? One key reason for analyzing and including HTTP request traffic is resilience. Having multiple sources of truth with respect to HTTP traffic allows us to better and more quickly distinguish between real events (such as an Internet disruption in a given country or network) and data pipeline issues.
While bytes-based metrics provide a reasonable proxy into human (user) behavior, especially with respect to activity surrounding Internet disruptions, request-based metrics provide an even better perspective. A lot of HTTP traffic involves relatively small responses – especially API traffic, which now accounts for 60% of all traffic. Furthermore, response sizes can vary widely, ranging from a single-pixel GIF accounting for just a few bytes, to an API call that returns a few kilobytes of data, to a multi-gigabyte software package
To that end, the scope of user activity may be insufficiently reflected by a bytes-based metric, or buried in the noise, whereas request activity provides a cleaner signal and a more direct proxy for user activity. This is especially important as we examine the restoration of connectivity after an Internet disruption, attempting to ascertain when activity has returned to “expected” pre-disruption levels.
Finally, incorporating request-based traffic insights into Radar is simply extending the way that the data is already being used on the site. All of the graphs, maps, and tables presented on Radar’s Adoption & Usage page, are based on analysis of HTTP request traffic, making use of information contained within request headers (such as HTTP version or user agent) or characteristics of the underlying connection (such as IP version).
Bytes vs requests – what’s the difference?
The current “HTTP traffic” view aggregates the bytes associated with HTTP requests to Cloudflare’s content delivery (CDN) services from the selected location or autonomous system (ASN). “Total traffic” aggregates this HTTP traffic along with the traffic associated with other Cloudflare services, including our 1.1.1.1 DNS resolver, authoritative DNS, WARP, and Spectrum, among others. (While Spectrum, WARP, and 1.1.1.1 also carry HTTP traffic, the share of HTTP traffic carried by these services is opaque to Radar, and isn’t accounted for as part of the HTTP traffic calculations.)
The bytes associated with a given request include the size of the request, the size of the headers associated with the response, and the size of the response itself. As noted above, the size of a file returned in response to a request can vary widely, depending on what was requested. The shape of the HTTP requests and HTTP bytes lines may be quite similar, but the potential variability in response sizes (in aggregate) can cause the lines to diverge, sometimes significantly so. For example, if an application regularly makes background requests to check for updates, the availability and subsequent download of a large file containing a software update would cause a spike in the HTTP bytes line, while the HTTP requests pattern remained consistent.
As another example, consider the graph below, capturing HTTP requests and bytes traffic trends for Portugal during the first week of August. HTTP bytes traffic initially grows each day between 06:00 and 09:00 UTC (07:00 – 10:00 local summer time), increases much more slowly until around 19:00 UTC (20:00 local summer time), and then increases rapidly before peaking around 21:00 UTC (22:00 local time). This suggests that content consumed during the workday is lighter in terms of bytes (such as API traffic, as discussed above), while evening traffic is more byte-heavy (possibly due to increased consumption of media content). In contrast, after starting to increase around 06:00 UTC (07:00 local summer time), request traffic generally sees three successively higher peaks each day – occurring around 10:00, 14:00, and 21:00 UTC respectively (11:00, 15:00, and 22:00 local summer time). These peaks are most pronounced on weekdays, but are still apparent on weekend days as well, suggesting regular patterns of user activity at those times.
It is important to remember that in looking at the “HTTP requests & bytes” graphs on Radar that they are showing two different metrics, and as such, only their shape over time is comparable, not their relative sizes. (As both metrics are normalized on a 0 to 1 (Max) scale, the lines on the graph are scaled relative to the maximum normalized value of each metric, including the previous period.)
Conclusion
The addition of HTTP request metrics to Cloudflare Radar brings additional visibility to traffic trends at a global, location, and network level, complementing the existing bytes-based HTTP traffic metrics. Derived from traffic to customer web properties, these new metrics can be found on Radar’s Overview and Traffic pages.
Last month, Backblaze Principal Storage Cloud Storyteller, Andy Klein, and I presented a webinar, Leveraging your Cloud Storage Data in AI/ML Apps and Services, in which we explored the various ways AI/ML applications use and store data. In addition to sharing insights from our customers who leverage Backblaze B2 Cloud Object Storage for their AI/ML needs, we also demonstrated a simple AI use case: a retrieval-augmented generation (RAG) chatbot answering questions based on custom context downloaded from a private Backblaze B2 Bucket. After the webinar, I posted the demo source code to a GitHub repository: https://github.com/backblaze-b2-samples/ai-rag-examples.
In this blog post, I’ll recap a little of the webinar, and explain how you can use the demo source code as a basis for your own experiments with RAG and large language models (LLMs).
But why, Pat?
You might be asking yourself, why build a chatbot when multiple online services, such as ChatGPT, are just a click away? It’s a good question. The main motivation is privacy. Suppose you want your chatbot to use confidential data in generating its responses. By running an LLM on your own machine, whether on-premises or on a virtual machine (VM) under your control in a public cloud provider’s infrastructure, you eliminate the risks of that data surfacing in response to a question from a user outside your organization.
In the webinar, I showed two Python apps running on a GPU-equipped VM at Vultr, one of Backblaze’s compute partners. The first app used the GPT4All Python SDK to create a very simple conversational chatbot running a local instance of a large language model (LLM), which it used in answering general questions. Here’s an example from the webinar:
Ask me a question: What were the causes of the First World War? The causes of the First World War are complex and varied, but some key factors include nationalism, imperialism, militarism, alliances between nations, and the assassination of Archduke Franz Ferdinand. Nationalism led to tensions between ethnic groups and their respective governments, while imperialism saw countries competing for territories and resources around the world. Militarism also played a role as many European powers built up large armies and navies in preparation for potential conflicts. The complex web of alliances between nations meant that any conflict could quickly escalate into a latIer war, and the assassination of Archduke Franz Ferdinand by a Serbian nationalist was the spark that ignited the powder keg of tensions already present in Europe at the time.
Now, I’m not a history scholar, but that looks like a pretty good answer to me! (History scholars, you are welcome to correct me.)
The second app used the Langchain framework to implement a more elaborate chatbot, again running on my own machine at Vultr, that used PDF data downloaded from a private bucket in Backblaze B2 as context for answering questions. As much as I love our webinar attendees, I didn’t want to share genuinely confidential data with them, so I used our Backblaze B2 Cloud Storage documentation as context. The chatbot was configured to use that context, and only that context, in answering questions. From the webinar:
Ask me a question about Backblaze 82: What's the difference between the master application key and a standard application key?
The master application key provides complete access to your account with all capabilities, access to all buckets, and has no file prefix restrictions or expiration. On the other hand, a standard application key is limited to the level of access that a user needs and can be specific to a bucket.
Ask me a question about Backblaze B2: What were the causes of the First World War?
The exact cause of the First World War is not mentioned in these documents.
The chatbot provides a comprehensive, accurate answer to the question on Backblaze application keys, but doesn’t answer the question on the causes of the First World War, since it was configured to use only the supplied context in generating its response.
During the webinar’s question-and-answer session, an attendee posed an excellent question: “Can you ask [the chatbot] follow-up questions where it can use previous discussions to build a proper answer based on content?” I responded, “Yes, absolutely; I’ll extend the demo to do exactly that before I post it to GitHub.” What follows are instructions for building a simple RAG chatbot, and then extending it to include message history.
Building a simple RAG chatbot
After the webinar, I rewrote both demo apps as Jupyter notebooks, which allowed me to add commentary to the code. I’ll provide you with edited highlights here, but you can find all of the details in the RAG demo notebook.
The first section of the notebook focuses on downloading PDF data from the private Backblaze B2 Bucket into a vector database, a storage mechanism particularly well suited for use with RAG. This process involves retrieving each PDF, splitting it into uniformly sized segments, and loading the segments into the database. The database stores each segment as a vector with many dimensions—we’re talking hundreds, or even thousands. The vector database can then vectorize a new piece of text—say a question from a user—and very quickly retrieve a list of matching segments.
Since this process can take significant time—about four minutes on my MacBook Pro M1 for the 225 PDF files I used, totaling 58MB of data—the notebook also shows you how to archive the resulting vector data to Backblaze B2 for safekeeping and retrieve it when running the chatbot later.
The vector database provides a “retriever” interface that takes a string as input, performs a similarity search on the vectors in the database, and outputs a list of matching documents. Given the vector database, it’s easy to obtain its retriever:
retriever = vectorstore.as_retriever()
The prompt template I used in the webinar provides the basic instructions for the LLM: use this context to answer the user’s question, and don’t go making things up!
prompt_template = """Use the following pieces of context to answer the question at the end.
    If you don't know the answer, just say that you don't know, don't try to make up an answer.

    {context}

    Question: {question}
    Helpful Answer:"""

prompt = PromptTemplate(
    template=prompt_template, input_variables=["context", "question"]
)
The RAG demo app creates a local instance of an LLM, using GPT4All with Nous Hermes 2 Mistral DPO, a fast chat-based model. Here’s an abbreviated version of the code:
model = GPT4All(
    model='Nous-Hermes-2-Mistral-7B-DPO.Q4_0.gguf',
    max_tokens=4096,
    device='gpu'
)
LangChain, as its name suggests, allows you to combine these components into a chain that can accept the user’s question and generate a response.
As mentioned above, the retriever takes the user’s question as input and returns a list of matching documents. The user’s question is also passed through the first step, and, in the second step, the prompt template combines the context with the user’s question to form the input to the LLM. If we were to peek inside the chain as it was processing the question about application keys, the prompt’s output would look something like this:
Use the following pieces of context to answer the question at the end. If you don't know the answer, just say that you don't know, don't try to make up an answer.

<Text of first matching document>

<Text of second matching document>

Question: What's the difference between the master application key and a standard application key?

Helpful Answer:
This is the basis of RAG: building an LLM prompt that contains the information required to generate an answer, then using the LLM to distill that prompt into an answer. The final step of the chain transforms the data structure emitted by the LLM into a simple string for display.
Now that we have a chain, we can ask it a question. Again, abbreviated from the sample code:
question = 'What is the difference between the master application key and a standard application key?'
answer = chain.invoke(question)
Adding message history to the simple RAG chatbot
The first step of extending the chatbot is to give the LLM new instructions, similar to its previous prompt template, but including the message history:
prompt_template = """Use the following pieces of context and the message history to answer the question at the end. If you don't know the answer, just say that you don't know, don't try to make up an answer.

Context: {context}

History: {history}

Question: {question}

Helpful Answer:"""

prompt = PromptTemplate(
    template=prompt_template, input_variables=["context", "question", "history"]
)
The chain must be modified slightly to accommodate the message history:
Now, we define a very simple in-memory message store that uses a session_id parameter to manage multiple simultaneous conversations:
store = {}

def get_session_history(session_id: str) -> BaseChatMessageHistory:
    if session_id not in store:
        store[session_id] = InMemoryChatMessageHistory()
    return store[session_id]
LangChain provides a wrapper, RunnableWithMessageHistory, that combines the message store with the above chain to create a new chain with message history capability:
Now we can feed a series of related questions into the new chain:
questions = [
    'What is the difference between the master application key and a standard application key?',
    'Which one would I use to work with a single bucket?',
    'Can you tell me anything more about this topic?'
]

for question in questions:
    print(f'\n{question}\n')
    answer = with_message_history.invoke(
        {"question": question},
        config={"configurable": {"session_id": "abc123"}},
    )
    print(f'{answer}\n')
I have to admit, I was pleasantly surprised by the results:
What is the difference between the master application key and a standard application key?
A master application key grants broad access privileges, while a standard application key is limited to the level of access that a user needs.
Which one would I use to work with a single bucket?
You would use a standard application key to work with a single bucket as it has limited access and only grants permissions needed for specific tasks, unlike the master application key which provides broad access privileges.
Can you tell me anything more about this topic?
Sure! The master application key is typically used by developers during development or testing phases to grant full access to all resources in a Backblaze B2 account, while the standard application key provides limited permissions and should be used for production environments where security is paramount.
Processing this series of questions on my MacBook Pro M1 with no GPU-acceleration took three minutes and 25 seconds, and just 52 seconds with its 16-core GPU. For comparison, I spun up a VM at Ori, another Backblaze partner offering GPU VM instances, with an Nvidia L4 Tensor Core GPU and 24GB of VRAM. The only code change required was to set the LLM device to ‘cuda’ to select the Nvidia GPU. The Ori VM answered those same questions in just 18 seconds.
The Nvidia L4 Tensor Core GPU: not much to look at, but crazy-fast AI inference!
Go forth and experiment
One of the reasons I refactored the demo apps was that notebooks allow an interactive, experimental approach. You can run the code in a cell, make a change, then re-run it to see the outcome. The RAG demo repository includes instructions for running the notebooks, and both the GPT4All and LangChain SDKs can run LLMs on machines with or without a GPU. Use the code as a starting point for your own exploration of AI, and let us know how you get on in the comments!
Version 6.4 of the Incus container manager is out.
This release builds upon the recently added OCI support from Incus
6.3, making it even easier to run application containers. It also
adds a number of useful new features for clustered and larger
environments with more control on the virtual CPU used when live
migrating VMs and finer grained resource constraints within
projects.
Security updates have been issued by Debian (kernel and roundcube), Fedora (microcode_ctl, pypy, python2.7, and python3.6), Oracle (389-ds-base, httpd, kernel, kernel-container, and linux-firmware), Red Hat (kernel-rt), SUSE (firefox, kubernetes1.23, libqt5-qtbase, openssl-1_1, python-gunicorn, python-Twisted, python-urllib3, and qt6-base), and Ubuntu (linux-aws-5.15, linux-gkeop-5.15, linux-ibm, linux-ibm-5.15, linux-raspi, linux-azure, linux-azure-5.15, linux-azure-fde, linux-azure-fde-5.15, linux-oem-6.8, linux-oracle-5.15, and qemu).
Historically, traffic graphs on Cloudflare Radar have displayed two metrics: total traffic and HTTP traffic. These graphs show normalized traffic volumes measured in bytes, derived from aggregated NetFlow data. (NetFlow is a protocol used to collect metadata about IP traffic flows traversing network devices.) Today, we’re adding another metric that reflects the number of HTTP requests, normalized over the same time period. By comparing bytes with requests, readers can gain additional insights into traffic patterns and user behavior. Below, we review how this new data has been incorporated into Radar, and explore HTTP request traffic in more detail.
Note that while we refer to “HTTP request traffic” in this post and on Radar, the term encompasses requests made in the clear over HTTP and over encrypted connections using HTTPS – the latter accounts for ~95% of all requests to Cloudflare during July 2024.
New and updated graphs
Graphs including HTTP request-based traffic data have been added to the Overview and Traffic sections on Cloudflare Radar. On the Overview page, the “Traffic trends” graph now includes a drop-down selector at the upper right, where you can choose between “Total & HTTP bytes” and “HTTP requests & bytes”. We explore the distinction between these further in the following sections.
The default “Total & HTTP bytes” selection displays a time series graph, showing total bytes and HTTP bytes traffic over time, as Radar has done for several years now.
Selecting “HTTP requests & bytes” from the dropdown switches the view to a time series graph that HTTP requests traffic and HTTP bytes traffic over time. In both graphs, users can click on a metric in the legend to deselect it and remove it from the graph. These (de)selections are maintained when a user chooses to download or save a graph.
In addition, we’ve added a “Protocols” summary next to the graph that shows the share of bytes over the selected time period that HTTP accounts for, and the remaining aggregate share associated with the protocols used by other non-HTTP Cloudflare services (such as DNS, WARP, etc.). For most locations or ASNs, HTTP traffic will comprise the majority share of bytes-based traffic.
On Radar’s Traffic page, we have added the HTTP requests metric to the “Traffic volume” graph at the top of the page, allowing you to see how request volume has changed during the selected time period as compared to the previous period, in addition to the changes in the bytes-based metrics.
A new standalone request-based “HTTP traffic” graph was also added to the Traffic page, just below the bytes-based “Traffic trends” graph. This new graph shows normalized HTTP request traffic volume across the selected time period, and by default, also compares it with the previous time period.
Similar to other Radar graphs, these new HTTP request-based graphs can also be downloaded, copied to the clipboard, or embedded in other websites – just click on the share icon.
As always, the underlying data is also available through the Radar API. The “HTTP requests Time Series” API endpoint returns normalized HTTP request time series data across the specified time period for the requested location or autonomous system (ASN).
What is HTTP request traffic?
An HTTP GET request is a message sent from a client (such as your web browser) to a web server (such as one operated by Cloudflare), asking for a particular resource (file). In addition to returning the requested resource, which could range from a single-pixel GIF accounting for just a few bytes, to an API call that returns a few kilobytes of data, to a multi-gigabyte software package, the Web server also returns a set of headers, which can include information about the content type, the last time the resource was modified, cookie information, cacheability, and more. While GET requests account for the overwhelming majority of HTTP request traffic, such traffic also includes other HTTP request methods including HEAD, POST, PUT, and more.
Cloudflare temporarily logs HTTP requests received by our network, including associated header information and “metadata” about the request, such as the bot score computed for the request and the associated cache status. Request logs for a customer’s web properties are available for them to download, and after processing and analysis, this data is also presented in the Analytics section of the Cloudflare dashboard. The HTTP request data now available on Radar is based on a sample of this log data, aggregated across Cloudflare’s global customer base.
The value of request-based traffic insights
Cloudflare Radar already has HTTP data, so why add more? One key reason for analyzing and including HTTP request traffic is resilience. Having multiple sources of truth with respect to HTTP traffic allows us to better and more quickly distinguish between real events (such as an Internet disruption in a given country or network) and data pipeline issues.
While bytes-based metrics provide a reasonable proxy into human (user) behavior, especially with respect to activity surrounding Internet disruptions, request-based metrics provide an even better perspective. A lot of HTTP traffic involves relatively small responses – especially API traffic, which now accounts for 60% of all traffic. Furthermore, response sizes can vary widely, ranging from a single-pixel GIF accounting for just a few bytes, to an API call that returns a few kilobytes of data, to a multi-gigabyte software package
To that end, the scope of user activity may be insufficiently reflected by a bytes-based metric, or buried in the noise, whereas request activity provides a cleaner signal and a more direct proxy for user activity. This is especially important as we examine the restoration of connectivity after an Internet disruption, attempting to ascertain when activity has returned to “expected” pre-disruption levels.
Finally, incorporating request-based traffic insights into Radar is simply extending the way that the data is already being used on the site. All the graphs, maps, and tables presented on Radar’s Adoption & Usage page, are based on analysis of HTTP request traffic, making use of information contained within request headers (such as HTTP version or user agent) or characteristics of the underlying connection (such as IP version).
Bytes vs requests – what’s the difference?
The current “HTTP traffic” view aggregates the bytes associated with HTTP requests to Cloudflare’s content delivery (CDN) services from the selected location or autonomous system (ASN). “Total traffic” aggregates this HTTP traffic along with the traffic associated with other Cloudflare services, including our 1.1.1.1 DNS resolver, authoritative DNS, WARP, and Spectrum, among others. (While Spectrum, WARP, and 1.1.1.1 also carry HTTP traffic, the share of HTTP traffic carried by these services is opaque to Radar, and isn’t accounted for as part of the HTTP traffic calculations.)
The bytes associated with a given request include the size of the request, the size of the headers associated with the response, and the size of the response itself. As noted above, the size of a file returned in response to a request can vary widely, depending on what was requested. The shape of the HTTP requests and HTTP bytes lines may be quite similar, but the potential variability in response sizes (in aggregate) can cause the lines to diverge, sometimes significantly so. For example, if an application regularly makes background requests to check for updates, the availability and subsequent download of a large file containing a software update would cause a spike in the HTTP bytes line, while the HTTP requests pattern remained consistent.
As another example, consider the graph below, capturing HTTP requests and bytes traffic trends for Portugal during the first week of August. HTTP bytes traffic initially grows each day between 06:00 and 09:00 UTC (07:00 – 10:00 local summer time), increases much more slowly until around 19:00 UTC (20:00 local summer time), and then increases rapidly before peaking around 21:00 UTC (22:00 local time). This suggests that content consumed during the workday is lighter in terms of bytes (such as API traffic, as discussed above), while evening traffic is more byte-heavy (possibly due to increased consumption of media content). In contrast, after starting to increase around 06:00 UTC (07:00 local summer time), request traffic generally sees three successively higher peaks each day – occurring around 10:00, 14:00, and 21:00 UTC respectively (11:00, 15:00, and 22:00 local summer time). These peaks are most pronounced on weekdays, but are still apparent on weekend days as well, suggesting regular patterns of user activity at those times.
It is important to remember that in looking at the “HTTP requests & bytes” graphs on Radar that they are showing two different metrics, and as such, only their shape over time is comparable, not their relative sizes. (As both metrics are normalized on a 0 to 1 (Max) scale, the lines on the graph are scaled relative to the maximum normalized value of each metric, including the previous period.)
Conclusion
The addition of HTTP request metrics to Cloudflare Radar brings additional visibility to traffic trends at a global, location, and network level, complementing the existing bytes-based HTTP traffic metrics. Derived from traffic to customer web properties, these new metrics can be found on Radar’s Overview and Traffic pages. In addition to HTTP traffic trends, visit Cloudflare Radar for additional insights around Internet disruptions, routing issues, attacks, domain popularity, and Internet quality. Follow us on social media at @CloudflareRadar (X), noc.social/@cloudflareradar (Mastodon), and radar.cloudflare.com (Bluesky), or contact us via email.
Really interesting article on the ancient-manuscript scholars who are applying their techniques to the Voynich Manuscript.
No one has been able to understand the writing yet, but there are some new understandings:
Davis presented her findings at the medieval-studies conference and published them in 2020 in the journal Manuscript Studies. She had hardly solved the Voynich, but she’d opened it to new kinds of investigation. If five scribes had come together to write it, the manuscript was probably the work of a community, rather than of a single deranged mind or con artist. Why the community used its own language, or code, remains a mystery. Whether it was a cloister of alchemists, or mad monks, or a group like the medieval Béguines—a secluded order of Christian women—required more study. But the marks of frequent use signaled that the manuscript served some routine, perhaps daily function.
Davis’s work brought like-minded scholars out of hiding. In just the past few years, a Yale linguist named Claire Bowern had begun performing sophisticated analyses of the text, building on the efforts of earlier scholars and on methods Bowern had used with undocumented Indigenous languages in Australia. At the University of Malta, computer scientists were figuring out how to analyze the Voynich with tools for natural-language processing. Researchers found that the manuscript’s roughly 38,000 words—and 9,000-word vocabulary—had many of the statistical hallmarks of actual language. The Voynich’s most common word, whatever it meant, appeared roughly twice as often as the second-most-common word and three times as often as the third-commonest, and so on—a touchstone of natural language known as Zipf’s law. The mix of word lengths and the ratio of unique words to total words were similarly language-like. Certain words, moreover, seemed to follow one another in predictable order, a possible sign of grammar.
Finally, each of the text’s sections—as defined by the drawings of plants, stars, bathing women, and so on—had different sets of overrepresented words, just as one would expect in a real book whose chapters focused on different subjects.
Spelling was the chief aberration. The Voynich alphabet—if that’s what it was—appeared to have a conventional 20-odd letters. But compared with known languages, too many of those letters repeated in the same order, both within words and across neighboring words, like a children’s rhyme. In some places, the spellings of adjacent words so converged that a single word repeated two or three times in a row. A rough English equivalent might be something akin to “She sells sea shells by the sea shore.” Another possibility, Bowern told me, was something like pig Latin, or the Yiddishism—known as “shm-reduplication”—that begets phrases such as fancy shmancy and rules shmules.
We’re thrilled to announce Cloudflare’s worldwide 2023 Channel Partner Award winners! Partners are crucial to Cloudflare’s success, extending the solutions and support that customers need to control application complexity, reduce cyber risk, and cut costs, all with a high level of customer satisfaction.
PowerUP Partners First
This year, we again received CRN’s highest accolade of a 5-star ranking for our Partner Program. Through our expandedCloudflare PowerUP Partner Program, we’re ensuring Cloudflare’s partnerships and alliances continue delivering strong results to joint customers across sectors worldwide. We’re focused on making it easier for our partners to work with us and grow their business with us. The Cloudflare team is all about helping partners:
Be innovative by transforming how customers connect, protect, and build with Cloudflare security, speed, programmability, and resilience.
Increase profitability by growing revenue and delivering more value at scale to rapidly grow business and expand reach.
Accelerate GTM by benefiting from sales and marketing support, streamlined processes, and transparent pricing to close deals quickly.
From comprehensive training through Cloudflare University to expert support across departments, partners are equipped to drive digital transformation and modernize IT infrastructures for their customers in a competitive market.
Leaders Who Understand the Power of Partnership
It’s been a thrilling start to my tenure as Cloudflare’s Chief Partner Officer to watch remarkable growth and partner success. Our team has amplified opportunities, especially in the rapidly expanding area of secure access service edge (SASE), and our channel strategy has already demonstrated impressive results.
The overwhelmingly positive feedback from our partners underscores the strength of Cloudflare’s technology and our dedication to serving our partners. With substantial investments in the partner community, streamlined processes, and a focus on AI integration, together we are poised to drive significant growth and innovation.
Congratulations to Our Partners’ Outstanding Contributions and Achievements
This year’s Cloudflare partner award winners have exemplified excellence and innovation in collaborating with Cloudflare. Their dedication and success highlight the transformative potential of the channel and our collaboration.
Americas Partner Awards
Technology Services Distributor of the Year: AVANT Communications
Honors the top-performing technology services distributor that has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Partner of the Year: GuidePoint Security
Honors the top-performing partner that has demonstrated phenomenal sales achievement in 2023.
Growth Partners of the Year: CDW and Defy Security
Honors the partners who made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Technical Excellence Award (Pre-Sales): Adapture
Honors the partner company who demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and proof of concept (POC) experience.
Partner SE Champion of the Year: Nyron Samaroo (CDW Canada) & Deepika Nath (Kyndryl) Honors the individual partner Sales Engineers (SEs) who have demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Global Systems Integrator (GSI) Partner of the Year: Accenture
Honors the top-performing GSI partner.
Latin America Awards
Technology Services Distributor of the Year: TD SYNNEX (LATAM)
Honors the top-performing technology services distributor that has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Partner of the Year: Honors the partner who, although new to the Cloudflare Partner Network in 2023, has already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
IntegraTEC (LATAM)
NeoSecure by SEK (Nola/Sola)
Cipher (Brazil)
Xenergix (Mexico)
Certification Champion of the Year: Tripla (Brazil)
This award honors the partner whose teams earned the highest total number of Cloudflare certifications during 2023.
APJC Partner Awards
Distributor of the Year: Dicker Data Limited
Honors the top performing distributor who has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Service Delivery Partner of the Year: Master Concept (Hong Kong) Ltd.
Honors the top-performing services solution provider.
Partner of the Year: Centcloud Technologies Limited
Honors the partner who, although new to the Cloudflare Partner Network in 2023, has already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Customer Win of the Year: Megazone Cloud Corporation
Honors the outstanding achievement of a partner who secured a significant customer deal through exceptional collaboration and innovation.
New Partner Win of the Year: Techdirect Pte Ltd
Honors the partner who has brought in the largest, most strategic deal and deployed a comprehensive end-to-end security, performance, and reliability solution to a customer.
Most Valuable Player of the Year: Omni Intelligent Services, Inc.
Honors top partner achievers who not only provided stellar service to our joint customers but also built new business value by tapping into the power of networks, relationships, and ecosystems.
Technical Excellence Award (Pre-Sales): Airowire Networks PVT LTD
Honors the partner company whose SEs demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and POC experience.
Marketing Champion of the Year: Softdebut Co.,Ltd
Honors the partner company that demonstrated outstanding collaboration and business outcomes in marketing Cloudflare solutions.
Partner SE Champion of the Year: David Woon (Kordia Limited)
Honors the individual partner SEs who have demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Rising Star Award: The Missing Link Security Pty Ltd
Honors individual partner representatives who, although new to our collaboration, have already made a significant, positive contribution both to our partnership and to driving outcomes for our customers.
Growth Partner of the Year: NTT Australia Pty Ltd
Honors the partner who made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
EMEA Partner Awards
Distributor of the Year: V-Valley advanced Solutions España SAU
Honors the top-performing distributor who has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
MSP of the Year: Orange Cyberdefense France
Honors the top-performing managed services solutions provider.
GSI of the Year: Eviden France SAS
Honors the top-performing GSI partner.
Partner of the Year: Liquid C2
Honors the top-performing partner that has demonstrated phenomenal sales achievement in 2023.
New Partner of the Year: Focus Group and Smartflare
Honors the partners who, although new to the Cloudflare Partner Network in 2023, have already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Customer Win of the Year: Liquid C2
Honors the outstanding achievement of a partner who secured a major customer deal through exceptional collaboration and innovation.
Rising Star Award: Copy Cat Group and Cloudhop
Honors individual partner representatives who, although new to our collaboration, have already made a significant, positive contribution both to our partnership and to driving outcomes for our customers.
Most Valuable Player of the Year: Nanosek
Honors the top partner achiever who not only provided stellar service to our joint customers but also built new business value by tapping into the power of networks, relationships, and ecosystems.
Technical Excellence Award (Pre-Sales):
Honors the partner company whose SEs demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and POC experience.
Jean-Baptiste Voron (Eviden France SAS)
Ganesh the Awesome (Globaldots)
Martin Campos (Orange Cyberdefense)
Partner SE Champion of the Year: Ivan Rudnytskyi (Bakotech s.r.o.)
Honors the individual partner SE who demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Certification Champion of the Year: Kaemi GmbH
This award honors the partner whose teams earned the highest total number of Cloudflare certifications during 2023.
Marketing Champion of the Year: Infinigate Deutschland GmbH and Alter Way
Honors partner companies who have demonstrated outstanding collaboration and business outcomes in marketing Cloudflare solutions.
To learn more about the Cloudflare PowerUP Partner Program, please check out the resources below:
We’re thrilled to announce Cloudflare’s worldwide 2023 Channel Partner Award winners! Partners are crucial to Cloudflare’s success, extending the solutions and support that customers need to control application complexity, reduce cyber risk, and cut costs, all with a high level of customer satisfaction.
PowerUP partners first
This year, we again received CRN’s highest accolade of a 5-star ranking for our Partner Program. Through our expanded Cloudflare PowerUP Partner Program, we’re ensuring Cloudflare’s partnerships and alliances continue delivering strong results to joint customers across sectors worldwide. We’re focused on making it easier for our partners to work with us and grow their business with us. The Cloudflare team is all about helping partners:
Be innovative by transforming how customers connect, protect, and build with Cloudflare security, speed, programmability, and resilience.
Increase profitability by growing revenue and delivering more value at scale to rapidly grow business and expand reach.
Accelerate GTM by benefiting from sales and marketing support, streamlined processes, and transparent pricing to close deals quickly.
From comprehensive training through Cloudflare University to expert support across departments, partners are equipped to drive digital transformation and modernize IT infrastructures for their customers in a competitive market.
Leaders who understand the power of partnership
It’s been a thrilling start to my tenure as Cloudflare’s Chief Partner Officer to watch remarkable growth and partner success. Our team has amplified opportunities, especially in the rapidly expanding area of secure access service edge (SASE), and our channel strategy has already demonstrated impressive results.
The overwhelmingly positive feedback from our partners underscores the strength of Cloudflare’s technology and our dedication to serving our partners. With substantial investments in the partner community, streamlined processes, and a focus on AI integration, together we are poised to drive significant growth and innovation.
Congratulations to our partners’ outstanding contributions and achievements
This year’s Cloudflare partner award winners have exemplified excellence and innovation in collaborating with Cloudflare. Their dedication and success highlight the transformative potential of the channel and our collaboration.
Americas partner awards
Technology Services Distributor of the Year: AVANT Communications Honors the top-performing technology services distributor that has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Partner of the Year: GuidePoint Security Honors the top-performing partner that has demonstrated phenomenal sales achievement in 2023.
Growth Partners of the Year: CDW and Defy Security Honors the partners who made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Technical Excellence Award (Pre-Sales): Adapture Honors the partner company who demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and proof of concept (POC) experience.
Partner SE Champion of the Year: Nyron Samaroo (CDW Canada) & Deepika Nath (Kyndryl) Honors the individual partner Sales Engineers (SEs) who have demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Global Systems Integrator (GSI) Partner of the Year: Accenture Honors the top-performing GSI partner.
Latin America awards
Technology Services Distributor of the Year: TD SYNNEX (LATAM) Honors the top-performing technology services distributor that has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Partner of the Year: Honors the partner who, although new to the Cloudflare Partner Network in 2023, has already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
IntegraTEC (LATAM)
NeoSecure by SEK (Nola/Sola)
Cipher (Brazil)
Xenergix (Mexico)
Certification Champion of the Year: Tripla (Brazil) This award honors the partner whose teams earned the highest total number of Cloudflare certifications during 2023.
APJC partner awards
Distributor of the Year: Dicker Data Limited Honors the top performing distributor who has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
Service Delivery Partner of the Year: Master Concept (Hong Kong) Ltd. Honors the top-performing services solution provider.
Partner of the Year: Centcloud Technologies Limited Honors the partner who, although new to the Cloudflare Partner Network in 2023, has already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Customer Win of the Year: Megazone Cloud Corporation Honors the outstanding achievement of a partner who secured a significant customer deal through exceptional collaboration and innovation.
New Partner Win of the Year: Techdirect Pte Ltd Honors the partner who has brought in the largest, most strategic deal and deployed a comprehensive end-to-end security, performance, and reliability solution to a customer.
Most Valuable Player of the Year: Omni Intelligent Services, Inc. Honors top partner achievers who not only provided stellar service to our joint customers but also built new business value by tapping into the power of networks, relationships, and ecosystems.
Technical Excellence Award (Pre-Sales): Airowire Networks PVT LTD Honors the partner company whose SEs demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and POC experience.
Marketing Champion of the Year: Softdebut Co., Ltd Honors the partner company that demonstrated outstanding collaboration and business outcomes in marketing Cloudflare solutions.
Partner SE Champion of the Year: David Woon (Kordia Limited) Honors the individual partner SEs who have demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Rising Star Award: The Missing Link Security Pty Ltd Honors individual partner representatives who, although new to our collaboration, have already made a significant, positive contribution both to our partnership and to driving outcomes for our customers.
Growth Partner of the Year: NTT Australia Pty Ltd Honors the partner who made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
EMEA partner awards
Distributor of the Year: V-Valley advanced Solutions España SAU Honors the top-performing distributor who has best represented Cloudflare and enabled partners to secure sales and growth revenue streams.
MSP of the Year: Orange Cyberdefense France Honors the top-performing managed services solutions provider.
GSI of the Year: Eviden France SAS Honors the top-performing GSI partner.
Partner of the Year: Liquid C2 Honors the top-performing partner that has demonstrated phenomenal sales achievement in 2023.
New Partner of the Year: Focus Group and Smartflare Honors the partners who, although new to the Cloudflare Partner Network in 2023, have already made substantial investments to grow our shared business, achieving not only full certification compliance but also exceeding revenue targets.
Customer Win of the Year: Liquid C2 Honors the outstanding achievement of a partner who secured a major customer deal through exceptional collaboration and innovation.
Rising Star Award: Copy Cat Group and Cloudhop Honors individual partner representatives who, although new to our collaboration, have already made a significant, positive contribution both to our partnership and to driving outcomes for our customers.
Most Valuable Player of the Year: Nanosek Honors the top partner achiever who not only provided stellar service to our joint customers but also built new business value by tapping into the power of networks, relationships, and ecosystems.
Technical Excellence Award (Pre-Sales): Honors the partner company whose SEs demonstrated great knowledge and expertise in leading the customer’s Cloudflare pre-sales and POC experience.
Jean-Baptiste Voron (Eviden France SAS)
Ganesh the Awesome (Globaldots)
Martin Campos (Orange Cyberdefense)
Partner SE Champion of the Year: Ivan Rudnytskyi (Bakotech s.r.o.) Honors the individual partner SE who demonstrated depth of knowledge and expertise in Cloudflare solutions and went above and beyond in delivering the Cloudflare experience for our joint customers.
Certification Champion of the Year: Kaemi GmbH This award honors the partner whose teams earned the highest total number of Cloudflare certifications during 2023.
Marketing Champion of the Year: Infinigate Deutschland GmbH and Alter Way Honors partner companies who have demonstrated outstanding collaboration and business outcomes in marketing Cloudflare solutions.
To learn more about the Cloudflare PowerUP Partner Program, please check out the resources below:
Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that enables you to analyze your data at scale. Amazon Redshift now allows you to programmatically access Amazon Redshift Advisor recommendations through an API, enabling you to integrate recommendations about how to improve your provisioned cluster performance into your own applications.
Amazon Redshift Advisor offers recommendations about optimizing your Redshift cluster performance and helps you save on operating costs. Advisor develops its customized recommendations by analyzing performance and usage metrics for your cluster and displays recommendations that should have a significant impact on performance and operations. Now, with the ability to programmatically access these recommendations through the ListRecommendations API, you can make recommendations available to implement on-demand or automatically through your own internal applications and tools without the need to access the Amazon Redshift console.
In this post, we show you how to use the ListRecommendations API to set up email notifications for Advisor recommendations on your Redshift cluster. These recommendations, such as identifying tables that should be vacuumed to sort the data or finding table columns that are candidates for compression, can help improve performance and save costs.
How to access Redshift Advisor recommendations
To access Advisor recommendations on the Amazon Redshift console, choose Advisor in the navigation pane. You can expand each recommendation to see more details, and sort and group recommendations.
You can also use the ListRecommendations API to automate receiving the Advisor recommendations and programmatically implement them. The API returns a list of recommended actions that can be parsed and implemented. The API and SDKs also enable you to set up workflows to use Advisor programmatically for automated optimizations. These automated periodic checks of Advisor using cron scheduling along with implementing the changes can help you keep Redshift clusters optimized automatically without manual intervention.
You can also use the list-recommendations command in the AWS Command Line Interface (AWS CLI) to invoke the Advisor recommendations from the command line and automate the workflow through scripts.
Solution overview
The following diagram illustrates the solution architecture.
The solution workflow consists of the following steps:
Complete the following steps to deploy the solution:
Choose Launch Stack.
For Stack name, enter a name for the stack, for example, blog-redshift-advisor-recommendations.
For SnsTopicArn, enter the SNS topic Amazon Resource Name (ARN) for receiving the email alerts.
For ClusterIdentifier, enter your Redshift cluster name if you want to receive Advisor notifications for a particular cluster. If you leave it blank, you will receive notifications for all Redshift provisioned clusters in your account.
For S3Bucket, enter the S3 bucket name to store the detailed Advisor recommendations in a JSON file. If you leave it blank, this step will be skipped.
For ScheduleExpression, enter the frequency in cron format to receive Advisor recommendation alerts. For this post, we want to receive alerts every Sunday at 14:00 UTC, so we enter cron(0 14 ? * SUN *).
Make sure to provide the correct cron time expression when deploying the CloudFormation stack to avoid any failures.
Keep all options as default under Configure Stack options and choose Next.
Review the settings, select the acknowledge check box, and create the stack.
Let’s take a closer look at the Lambda function and the complete workflow.
The input values provided for SnsTopicArn, ClusterIdentifier, and S3Bucket in the CloudFormation stack creation are set as environmental variables in the Lambda function. If the ClusterIdentifier parameter is None, then it will invoke the ListRecommendations API to generate Advisor recommendations for all the clusters within the account (same AWS Region). Otherwise, it will pass the ClusterIdentifier value and generate Advisor recommendations only for the given cluster. If the input parameter S3Bucket is provided, the solution creates a folder named RedshiftAdvisorRecommendations and generates the Advisor recommendations file in JSON format within it. If a value for S3Bucket isn’t provided, this step will be skipped.
Next, the function will summarize recommendations by each provisioned cluster (for all clusters in the account or a single cluster, depending on your settings) based on the impact on performance and cost as HIGH, MEDIUM, and LOW categories. An SNS notification email will be sent to the subscribers with the summarized recommendations.
SQL commands are included as part of the Advisor’s recommended action. RecommendedActionType-SQL summarizes the number of SQL actions that can be applied using SQL commands.
If there are no recommendations available for any cluster, the SNS notification email will be sent notifying there are no Advisor recommendations.
An EventBridge rule is created to invoke the Lambda function based on the frequency you provided in the stack parameters. By default, it’s scheduled to run weekly each Sunday at 14:00 UTC.
The following is a screenshot of a sample SNS notification email.
Clean up
We recommend deleting the CloudFormation stack if you aren’t going to continue using the solution. This will avoid incurring any additional costs from the resources created as part of the solution.
Conclusion
In this post, we discussed how Redshift Advisor offers you specific recommendations to improve the performance of and decrease the operating costs for your Redshift cluster. We also showed you how to programmatically access these recommendations through an API and implement them on-demand or automatically using your own internal tools without having access to the Amazon Redshift console.
By integrating these recommendations into your workflows, you can make informed decisions and implement best practices to optimize the performance and costs of your Redshift clusters, ultimately enhancing the overall efficiency and productivity of your data processing operations.
We encourage you to try out this automated solution to access Advisor recommendations programmatically. If you have any feedback or questions, please leave them in the comments.
About the authors
Ranjan Burman is an Analytics Specialist Solutions Architect at AWS. He specializes in Amazon Redshift and helps customers build scalable analytical solutions. He has more than 16 years of experience in different database and data warehousing technologies. He is passionate about automating and solving customer problems with cloud solutions.
Nita Shah is a Senior Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.
Vamsi Bhadriraju is a Data Architect at AWS. He works closely with enterprise customers to build data lakes and analytical applications on the AWS Cloud.
Sumant Nemmani is a Senior Technical Product Manager at AWS. He is focused on helping customers of Amazon Redshift benefit from features that use machine learning and intelligent mechanisms to enable the service to self-tune and optimize itself, ensuring Redshift remains price-performant as they scale their usage.
Linux hardware vendor System76 started promoting
its work on a Rust-based, Wayland
desktop environment for its Pop!_OS
Ubuntu-derivative distribution almost two years
ago. On August 8, the company released an alpha version of the COSMIC desktop environment for
users to test out. While it has rough edges and missing features, it
is stable enough to get a good feel for what the finished product has
in store—and the initial results are promising.
When Dr. Swami Sivasubramanian, VP of AI and Data, was an intern at Amazon in 2005, Dr. Werner Vogels, CTO of Amazon, was his first manager. Nineteen years later, the two shared a stage at the VivaTech Conference to reflect on Amazon’s history of innovation—from pioneering the pay-as-you-go model with Amazon Web Services (AWS) to transforming customer experiences using “good old-fashioned AI”—as well as what really keeps them up at night in the age of generative artificial intelligence (generative AI).
Asked if competitors ever kept him up at night, Dr. Werner insisted that listening to customer needs—such as guardrails, security, and privacy—and building products based on those needs is what drives success at Amazon. Dr. Swami said he viewed Amazon SageMaker and Amazon Bedrock as prime examples of successful products that have emerged as a result of this customer-first approach. “If you end up chasing your competitors, you are going to end up building what they are building,” he added. “If you actually listen to your customers, you are actually going to lead the way in innovation.” To learn four more lessons on customer-obsessed innovation, visit our AWS Careers blog.
For example, for customer-obsessed security, we build and use Mithra, a powerful neural network model to detect and respond to cyber threats. It analyzes up to 200 trillion internet domain requests daily from the AWS global network, identifying an average of 182,000 new malicious domains with remarkable accuracy. Mithra is just one example of how AWS uses global scale, advanced artificial intelligence and machine learning (AI/ML) technology, and constant innovation to lead the way in cloud security, making the internet safer for everyone. To learn more, visit the blog post of Chief Information Security Officer at Amazon CJ Moses, How AWS tracks the cloud’s biggest security threats and helps shut them down.
Last week’s launches Here are some launches that got my attention:
Regional expansion of Anthropic’s Claude models in Amazon Bedrock – The Claude 3.5 Sonnet, Anthropic’s latest high-performance AI model, is now available in US West (Oregon), Europe (Frankfurt), Asia Pacific (Tokyo), and Asia Pacific (Singapore) Regions in Amazon Bedrock. The Claude 3 Haiku, Anthropic’s compact and affordable AI model, is now available in Asia Pacific (Tokyo) and Asia Pacific (Singapore) Regions in Amazon Bedrock.
Up to 30 GiB/s of read throughput in Amazon EFS – We are increasing the read throughput to 30 GiB/s, extending simple, fully elastic, and provisioning-free experience of Amazon EFS to support throughput-intensive AI and ML workloads for model training, inference, financial analytics, and genomic data analysis.
Large language models (LLMs) in Amazon Redshift ML – You can use pre-trained publicly available LLMs in Amazon SageMaker JumpStart as part of Amazon Redshift ML. For example, you can use LLMs to summarize feedback, perform entity extraction, and conduct sentiment analysis on data in your Amazon Redshift table, so you can bring the power of generative AI to your data warehouse.
Data products in Amazon DataZone – You can create data products in Amazon DataZone, which enable the grouping of data assets into well-defined, self-contained packages tailored for specific business use cases. For example, a marketing analysis data product can bundle various data assets such as marketing campaign data, pipeline data, and customer data. To learn more, visit this AWS Big Data blog post.
Other AWS news Here are some additional news items that you might find interesting:
AWS Goodies by Jeff Barr – Want to discover more exciting news about AWS? Jeff Barr is always in catch-up mode, doing his best to share all of the interesting things that he finds or that are shared with him. You can find his goodies once a week. Follow his LinkedIn page.
AWS and Multicloud – You might have missed a great article about the existing capabilities AWS has and the continued enhancements we’ve made in multicloud environments. In the post, Jeff covers the AWS approach to multicloud, provides you with some real-world examples, and reviews some of the newest multicloud and hybrid capabilities found across the lineup of AWS services.
Code transformation in Amazon Q Developer – At Amazon, we asked a small team to use Amazon Q Developer Agent for code transformation to migrate more than 30,000 production applications from older Java versions to Java 17. By using Amazon Q Developer to automate these upgrades, the team saved over 4,500 developer years of effort compared to what it would have taken to do all of these upgrades manually and saved the company $260 million in annual savings by moving to the latest Java version.
Contributing to AWS CDK – AWS Cloud Development Kit (AWS CDK) is an open source software development framework to model and provision your cloud application resources using familiar programming languages. Contributing to AWS CDK not only helps you deepen your knowledge of AWS services but also allows you to give back to the community and improve a tool you rely on.
Upcoming AWS events Check your calendars and sign up for these AWS events:
AWS re:Invent 2024 – Dive into the first-round session catalog. Explore all the different learning opportunities at AWS re:Invent this year and start building your agenda today. You’ll find sessions for all interests and learning styles.
AWS Innovate Migrate, Modernize, Build – Learn about proven strategies and practical steps for effectively migrating workloads to the AWS Cloud, modernizing applications, and building cloud-native and AI-enabled solutions. Don’t miss this opportunity to learn with the experts and unlock the full potential of AWS. Register now for Asia Pacific, Korea, and Japan (September 26).
AWS Summits – The 2024 AWS Summit season is almost wrapping up! Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: São Paulo (August 15), Jakarta (September 5), and Toronto (September 11).
AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: New Zealand (August 15), Colombia (August 24), New York (August 28), Belfast (September 6), and Bay Area (September 13).
AWS GenAI Lofts – Meet AWS AI experts and attend talks, workshops, fireside chats, and Q&As with industry leaders. All lofts are free and are carefully curated to offer something for everyone to help you accelerate your journey with AI. There are lofts scheduled in San Francisco (August 14–September 27), São Paulo (September 2–November 20), London (September 30–October 25), Paris (October 8–November 25), and Seoul (November).
Version 4.0 of the Magit text-based
Git user interface for Emacs has been released. Changes since the 3.3.0
release include the addition of context menus, a makeover for the
menu-bar menu, new menu commands, and many other new features and bug
fixes. See the release
notes for full details.
Security updates have been issued by AlmaLinux (httpd:2.4), Fedora (chromium, firefox, frr, neatvnc, nss, python-setuptools, and python3.13), Gentoo (AFLplusplus, Bundler, dpkg, GnuPG, GPAC, libde265, matio, MuPDF, PHP, protobuf, protobuf-python, protobuf-c, rsyslog, Ruby on Rails, and runc), Red Hat (389-ds-base, container-tools:rhel8, and httpd:2.4), SUSE (bind and ca-certificates-mozilla), and Ubuntu (linux-azure).
For many years, Cloudflare has used advanced fingerprinting techniques to help block online threats, in products like our DDoS engine, our WAF, and Bot Management. For the purposes of Bot Management, fingerprinting characteristic elements of client software help us quickly identify what kind of software is making an HTTP request. It’s an efficient and accurate way to differentiate a browser from a Python script, while preserving user privacy. These fingerprints are used on their own for simple rules, and they underpin complex machine learning models as well.
Making sure our fingerprints keep pace with the pace of change on the Internet is a constant and critical task. Bots will always adapt to try and look more browser-like. Less frequently, browsers will introduce major changes to their behavior and affect the entire Internet landscape. Last year, Google did exactly that, making older TLS fingerprints almost useless for identifying the latest version of Chrome.
JA3 Fingerprint
JA3 fingerprint introduced by Salesforce researchers in 2017 and later adopted by Cloudflare, involves creating a hash of the TLS ClientHello message. This hash includes the ordered list of TLS cipher suites, extensions, and other parameters, providing a unique identifier for each client. Cloudflare customers can use JA3 to build detection rules and gain insight into their network traffic.
In early 2023, Google implemented a change in Chromium-based browsers to shuffle the order of TLS extensions – a strategy aimed at disrupting the detection capabilities of JA3 and enhancing the robustness of the TLS ecosystem. This modification was prompted by concerns that fixed fingerprint patterns could lead to rigid server implementations, potentially causing complications each time Chrome updates were rolled out. Over time, JA3 became less useful due to the following reasons:
Randomization of TLS extensions: Browsers began randomizing the order of TLS extensions in their ClientHello messages. This change meant that the JA3 fingerprints, which relied on the sequential order of these extensions, would vary with each connection, making it unreliable for identifying unique clients. (Further information can be found at Stamus Networks.)
Inconsistencies across tools: Different tools and databases that implemented JA3 fingerprinting often produced varying results due to discrepancies in how they handled TLS extensions and other protocol elements. This inconsistency hindered the effectiveness of JA3 fingerprints for reliable cross-organization sharing and threat intelligence. (Further information can be found at Fingerprint.)
Limited scope and lack of adaptability: JA3 focused solely on elements within the TLS ClientHello packet, covering only a narrow portion of the OSI model’s layers. This limited scope often missed crucial context about a client’s environment. Additionally, as newer transport layer protocols like QUIC became popular, JA3’s methodology – originally designed for older client implementations of TLS and not including modern protocols – proved ineffective.
Enter JA4 fingerprint
In response to these challenges, FoxIO developed JA4, a successor to JA3 that offers a more robust, adaptable, and reliable method for fingerprinting TLS clients across various protocols, including emerging standards like QUIC. Officially launched in September 2023, JA4 is part of the broader JA4+ suite that includes fingerprints for multiple protocols such as TLS, HTTP, and SSH. This suite is designed to be interpretable by both humans and machines, thereby enhancing threat detection and security analysis capabilities.
JA4 fingerprint is resistant to the randomization of TLS extensions and incorporates additional useful dimensions, such as Application Layer Protocol Negotiation (ALPN), which were not part of JA3. The introduction of JA4 has been met with positive reception in the cybersecurity community, with several open-source tools and commercial products beginning to incorporate it into their systems, including Cloudflare. The JA4 fingerprint is available under the BSD 3-Clause license, promoting seamless upgrades from JA3. Other fingerprints within the suite, such as JA4S (TLS Server Response) and JA4H (HTTP Client Fingerprinting), are licensed under the proprietary FoxIO License, which is designed for broader use but requires specific arrangements for commercial monetization.
Let’s take a look at specific JA4 fingerprint example, representing the latest version of Google Chrome on Linux:
Protocol Identifier (t): Indicates the use of TLS over TCP. This identifier is crucial for determining the underlying protocol, distinguishing it from q for QUIC or d for DTLS.
TLS Version (13): Represents TLS version 1.3, confirming that the client is using one of the latest secure protocols. The version number is derived from analyzing the highest version supported in the ClientHello, excluding any GREASE values.
SNI Presence (d): The presence of a domain name in the Server Name Indication. This indicates that the client specifies a domain (d), rather than an IP address (i would indicate the absence of SNI).
Cipher Suites Count (15): Reflects the total number of cipher suites included in the ClientHello, excluding any GREASE values. It provides insight into the cryptographic options the client is willing to use.
Extensions Count (16): Indicates the count of distinct extensions presented by the client in the ClientHello. This measure helps identify the range of functionalities or customizations the client supports.
ALPN Values (h2): Represents the Application-Layer Protocol Negotiation protocol, in this case, HTTP/2, which indicates the protocol preferences of the client for optimized web performance.
Cipher Hash (8daaf6152771): A truncated SHA256 hash of the list of cipher suites, sorted in hexadecimal order. This unique hash serves as a compact identifier for the client’s cipher suite preferences.
Extension Hash (02713d6af862): A truncated SHA256 hash of the sorted list of extensions combined with the list of signature algorithms. This hash provides a unique identifier that helps differentiate clients based on the extensions and signature algorithms they support.
Integrating JA4 support into Cloudflare required rethinking our approach to parsing TLS ClientHello messages, which were previously handled in separate implementations across C, Lua, and Go. Recognizing the need to boost performance and ensure memory safety, we developed a new Rust-based crate, client-hello-parser. This unified parser not only simplifies modifications by centralizing all related logic but also prepares us for future transitions, such as replacing nginx with an upcoming Rust-based service. Additionally, this streamlined parser facilitates the exposure of JA4 fingerprints across our platform, improving the integration with Cloudflare’s firewall rules, Workers, and analytics systems.
Parsing ClientHello
client-hello-parser is an internal Rust crate designed for parsing TLS ClientHello messages. It aims to simplify the process of analyzing TLS traffic by providing a straightforward way to decode and inspect the initial handshake messages sent by clients when establishing TLS connections. This crate efficiently populates a ClientHelloParsed struct with relevant parsed fields, including version 1 and version 2 fingerprints, and JA3 and JA4 hashes, which are essential for network traffic analysis and fingerprinting.
Key benefits of the client-hello-parser library include:
Optimized memory usage: The library achieves amortized zero heap allocations, verified through extensive testing with the dhat crate to track memory allocations. Utilizing the tiny_vec crate, it begins with stack allocations for small vectors backed by fixed-size arrays, resorting to heap allocations only when these vectors exceed their initial size. This method ensures efficient reuse of all vectors, maintaining amortized zero heap allocations.
Memory safety: Reinforced by Rust’s robust borrow checker and complemented by extensive fuzzing, which has helped identify and resolve potential security vulnerabilities previously undetected in C implementations.
Ultra-low latency: The parser benefits from using faster_hex for efficient hex encoding/decoding, which utilizes SIMD instructions to speed up processing. The use of Rust iterators also helps in optimizing performance, often allowing the compiler to generate SIMD-optimized assembly code. This efficiency is further enhanced through the use of BigEndianIterator, which allows for efficient streaming-like processing of TLS ClientHello bytes in a single pass.
The benchmark results demonstrate that the parser efficiently handles different sizes of ClientHello messages, with shorter messages being processed at a rate of approximately 2 million elements per second, and longer messages at around 1 million elements per second, showcasing the effectiveness of SIMD optimizations and Rust’s iterator performance in real-world applications.
Robust testing suite: Includes dozens of real-life TLS ClientHello message examples, with parsed components verified against Wireshark with JA3 and JA4 plugins. Additionally, Cargo fuzzer with memory sanitizer ensures no memory leaks or edge cases leading to core dumps. Backward compatibility tests with the legacy C parser, imported as a dependency and called via FFI, confirm that both parsers yield equivalent results.
Seamless integration with nginx: The crate, compiled as a dynamic library, is linked to the nginx binary, ensuring a smooth transition from the legacy parser to the new Rust-based parser through backwards compatibility tests.
The transition to a new Rust-based parser has enabled the retirement of multiple implementations across different languages (C, Lua, and Go), significantly enhancing performance and parser robustness against edge cases. This shift also facilitates the easier integration of new features and business logic for parsing TLS ClientHello messages, streamlining future expansions and security updates.
With Cloudflare JA4 fingerprints implemented on our network, we were left with another problem to solve. When JA3 was released, we saw some scenarios where customers were surprised by traffic from a new JA3 fingerprint and blocked it, only to find the fingerprint was a new browser release, or an OS update had caused a change in the fingerprint used by their mobile device. By giving customers just a hash, customers still lack context. We wanted to give our customers the necessary context to help them make informed decisions about the safety of a fingerprint, so they can act quickly and confidently on it. As more of our customers embrace AI, we’ve heard more demand from our customers to break out the signals that power our bot detection. These customers want to run complex models on proprietary data that has to stay in their control, but they want to have Cloudflare’s unique perspective on Internet traffic when they do it. To us, both use cases sounded like the same problem.
Enter JA4 Signals
In the ever-evolving landscape of web security, traditional fingerprinting techniques like JA3 and JA4 have proven invaluable for identifying and managing web traffic. However, these methods alone are not sufficient to address the sophisticated tactics employed by malicious agents. Fingerprints can be easily spoofed, they change frequently, and traffic patterns and behaviors are constantly evolving. This is where JA4 Signals come into play, providing a robust and comprehensive approach to traffic analysis.
JA4 Signals are inter-request features computed based on the last hour of all traffic that Cloudflare sees globally. On a daily basis, we analyze over 15 million unique JA4 fingerprints generated from more than 500 million user agents and billions of IP addresses. This breadth of data enables JA4 Signals to provide aggregated statistics that offer deeper insights into global traffic patterns – far beyond what single-request or connection fingerprinting can achieve. These signals are crucial for enhancing security measures, whether through simple firewall rules, Workers scripts, or advanced machine learning models.
Let’s consider a specific example of JA4 Signals from a Firewall events activity log, which involves the latest version of Chrome:
This example highlights that a particular HTTP request received a Bot Score of 95, suggesting it likely originated from a human user operating a browser rather than an automated program or a bot. Analyzing JA4 Signals in this context provides deeper insight into the behavior of this client (latest Linux Chrome) in comparison to other network clients and their respective JA4 fingerprints. Here are a few examples of the signals our customers can see on any request:
JA4 Signal
Description
Value example
Interpretation
browser_ratio_1h
The ratio of requests originating from browser-based user agents for the JA4 fingerprint in the last hour. Higher values suggest a higher proportion of browser-based requests.
0.942
Indicates a 94.2% browser-based request rate for this JA4.
cache_ratio_1h
The ratio of cacheable responses for the JA4 fingerprint in the last hour. Higher values suggest a higher proportion of responses that can be cached.
0.534
Shows a 53.4% cacheable response rate for this JA4.
h2h3_ratio_1h
The ratio of HTTP/2 and HTTP/3 requests combined with the total number of requests for the JA4 fingerprint in the last hour. Higher values indicate a higher proportion of HTTP/2 and HTTP/3 requests compared to other protocol versions.
0.987
Reflects a 98.7% rate of HTTP/2 and HTTP/3 requests.
reqs_quantile_1h
The quantile position of the JA4 fingerprint based on the number of requests across all fingerprints in the last hour. Higher values indicate a relatively higher number of requests compared to other fingerprints.
1
High volume of requests compared to other JA4s.
The JA4 fingerprint and JA4 Signals are now available in the Firewall Rules UI, Bot Analytics and Workers. Customers can now use these fields to write custom rules, rate-limiting rules, transform rules, or Workers logic using JA4 fingerprint and JA4 Signals.
Let’s demonstrate how to use JA4 Signals with the following Worker example. This script processes incoming requests by parsing and categorizing JA4 Signals, providing a clear structure for further analysis or rule application within Cloudflare Workers:
/**
 * Event listener for 'fetch' events. This triggers on every request to the worker.
 */
addEventListener('fetch', event => {
  event.respondWith(handleRequest(event.request))
})

/**
 * Main handler for incoming requests.
 * @param {Request} request - The incoming request object from the fetch event.
 * @returns {Response} A response object with JA4 Signals in JSON format.
 */
async function handleRequest(request) {
  // Safely access the ja4Signals object using optional chaining, which prevents errors if properties are undefined.
  const ja4Signals = request.cf?.botManagement?.ja4Signals || {};

  // Construct the response content, including both the original ja4Signals and the parsed signals.
  const responseContent = {
    ja4Signals: ja4Signals,
    jaSignalsParsed: parseJA4Signals(ja4Signals)
  };

  // Return a JSON response with appropriate headers.
  return new Response(JSON.stringify(responseContent), {
    status: 200,
    headers: {
      "content-type": "application/json;charset=UTF-8"
    }
  })
}

/**
 * Parses the JA4 Signals into categorized groups based on their names.
 * @param {Object} ja4Signals - The JA4 Signals object that may contain various metrics.
 * @returns {Object} An object with categorized JA4 Signals: ratios, ranks, and quantiles.
 */
function parseJA4Signals(ja4Signals) {
  // Define the keys for each category of signals.
  const ratios = ['h2h3_ratio_1h', 'heuristic_ratio_1h', 'browser_ratio_1h', 'cache_ratio_1h'];
  const ranks = ['uas_rank_1h', 'paths_rank_1h', 'reqs_rank_1h', 'ips_rank_1h'];
  const quantiles = ['reqs_quantile_1h', 'ips_quantile_1h'];

  // Return an object with each category containing only the signals that are present.
  return {
    ratios: filterKeys(ja4Signals, ratios),
    ranks: filterKeys(ja4Signals, ranks),
    quantiles: filterKeys(ja4Signals, quantiles)
  };
}

/**
 * Filters the keys in the ja4Signals object that match the list of specified keys and are not undefined.
 * @param {Object} ja4Signals - The JA4 Signals object.
 * @param {Array} keys - An array of keys to filter from the ja4Signals object.
 * @returns {Object} A filtered object containing only the specified keys that are present in ja4Signals.
 */
function filterKeys(ja4Signals, keys) {
  const filtered = {};
  // Iterate over the specified keys and add them to the filtered object if they exist in ja4Signals.
  keys.forEach(key => {
    // Check if the key exists and is not undefined to handle optional presence of each signal.
    if (ja4Signals && ja4Signals[key] !== undefined) {
      filtered[key] = ja4Signals[key];
    }
  });
  return filtered;
}
Benefits of JA4 Signals
Comprehensive traffic analysis: JA4 Signals aggregate data over an hour to provide a holistic view of traffic patterns. This method enhances the ability to identify emerging threats and abnormal behaviors by analyzing changes over time rather than in isolation.
Precision in anomaly detection: Leveraging detailed inter-request features, JA4 Signals enable the precise detection of anomalies that may be overlooked by single-request fingerprinting. This leads to more accurate identification of sophisticated cyber threats.
Globally scalable insights: By synthesizing data at a global scale, JA4 Signals harness the strength of Cloudflare’s network intelligence. This extensive analysis makes the system less susceptible to manipulation and provides a resilient foundation for security protocols.
Dynamic security enforcement: JA4 Signals can dynamically inform security rules, from simple firewall configurations to complex machine learning algorithms. This adaptability ensures that security measures evolve in tandem with changing traffic patterns and emerging threats.
Reduction in false positives and negatives: With the detailed insights provided by JA4 Signals, security systems can distinguish between legitimate and malicious traffic more effectively, reducing the occurrence of false positives and negatives and improving overall system reliability.
Conclusion
The introduction of JA4 fingerprint and JA4 Signals marks a significant milestone in advancing Cloudflare’s security offerings, including Bot Management and DDoS protection. These tools not only enhance the robustness of our traffic analysis but also showcase the continuous evolution of our network fingerprinting techniques. The efficiency of computing JA4 fingerprints enables real-time detection and response to emerging threats. Similarly, by leveraging aggregated statistics and inter-request features, JA4 Signals provide deep insights into traffic patterns at speeds measured in microseconds, ensuring that no detail is too small to be captured and analyzed.
These security features are underpinned by the scalable techniques and open-sourced libraries outlined in “Every request, every microsecond: scalable machine learning at Cloudflare”. This discussion highlights how Cloudflare’s innovations not only analyze vast amounts of data but also transform this analysis into actionable, reliable, and dynamically adaptable security measures.
Any Enterprise business with a bot problem will benefit from Cloudflare’s unique JA4 implementation and our perspective on bot traffic, but customers who run their own internal threat models will also benefit from access to data insights from a network that processes over 50 million requests per second. Please get in touch with us to learn more about our Bot Management offering.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


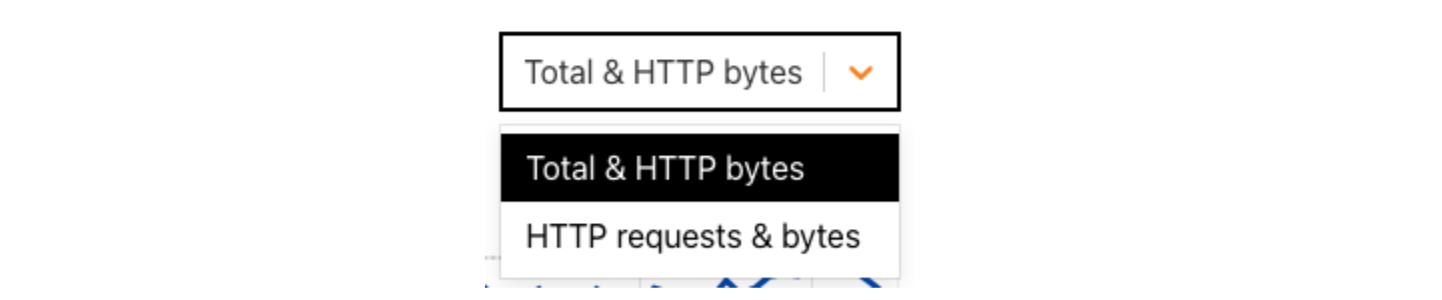
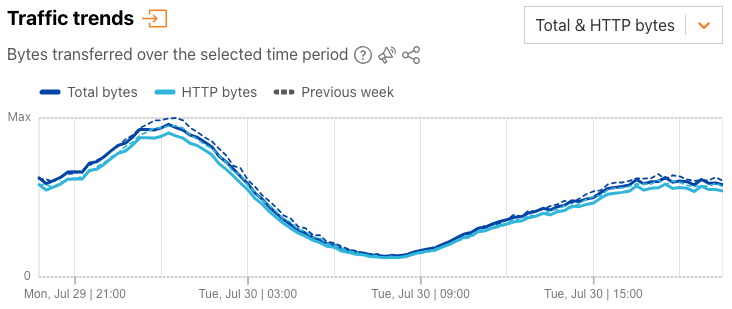
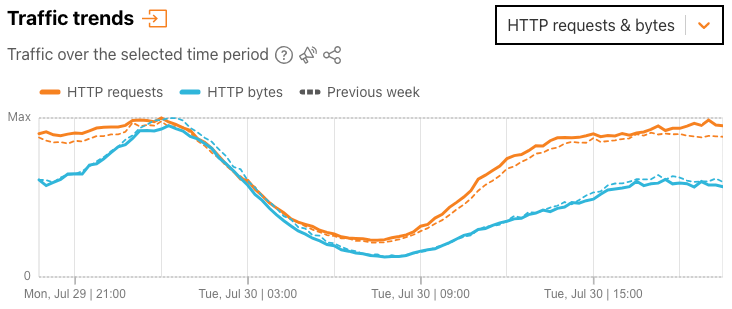
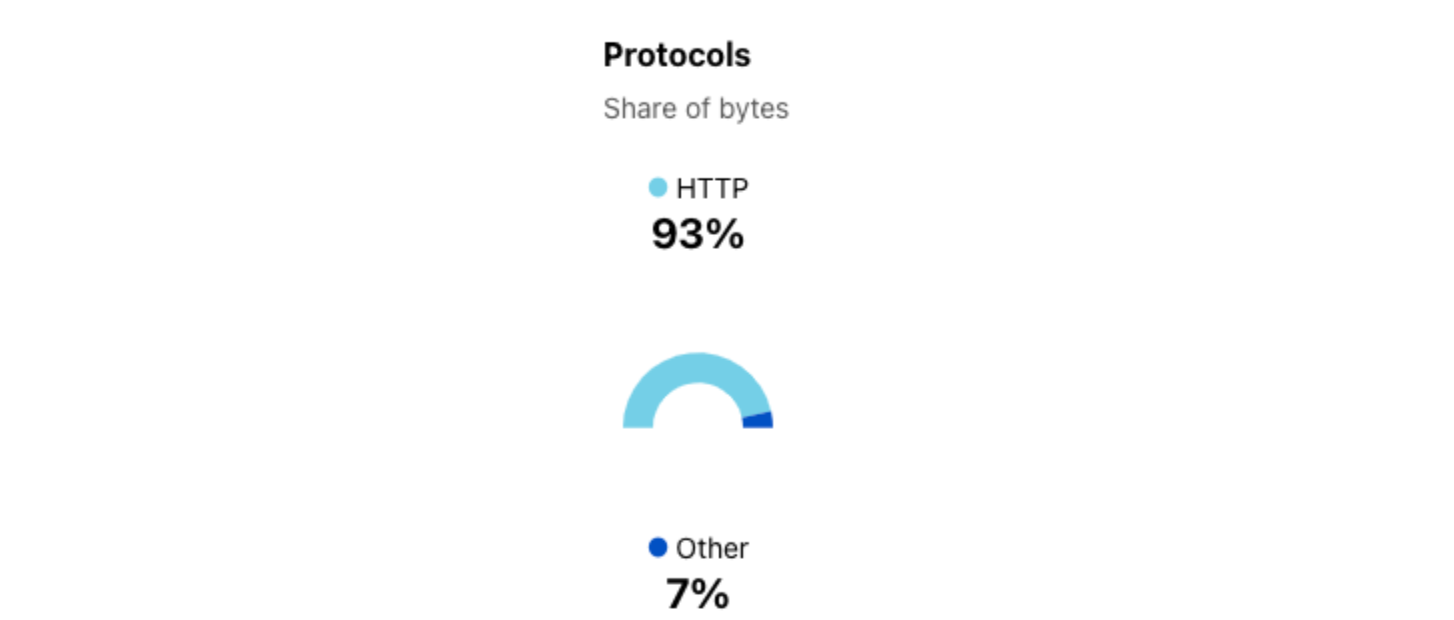
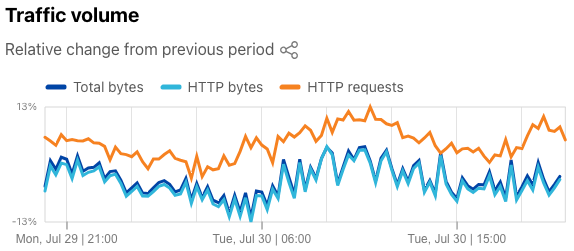
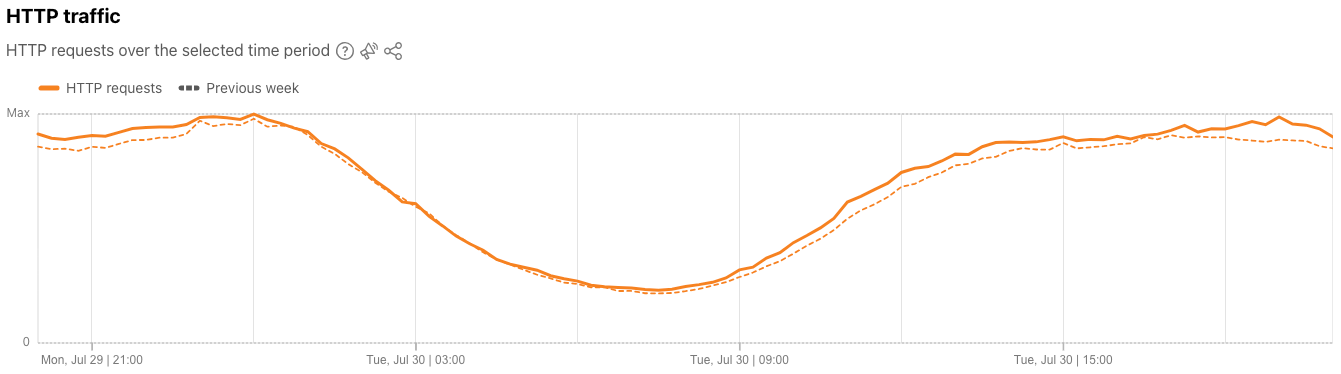
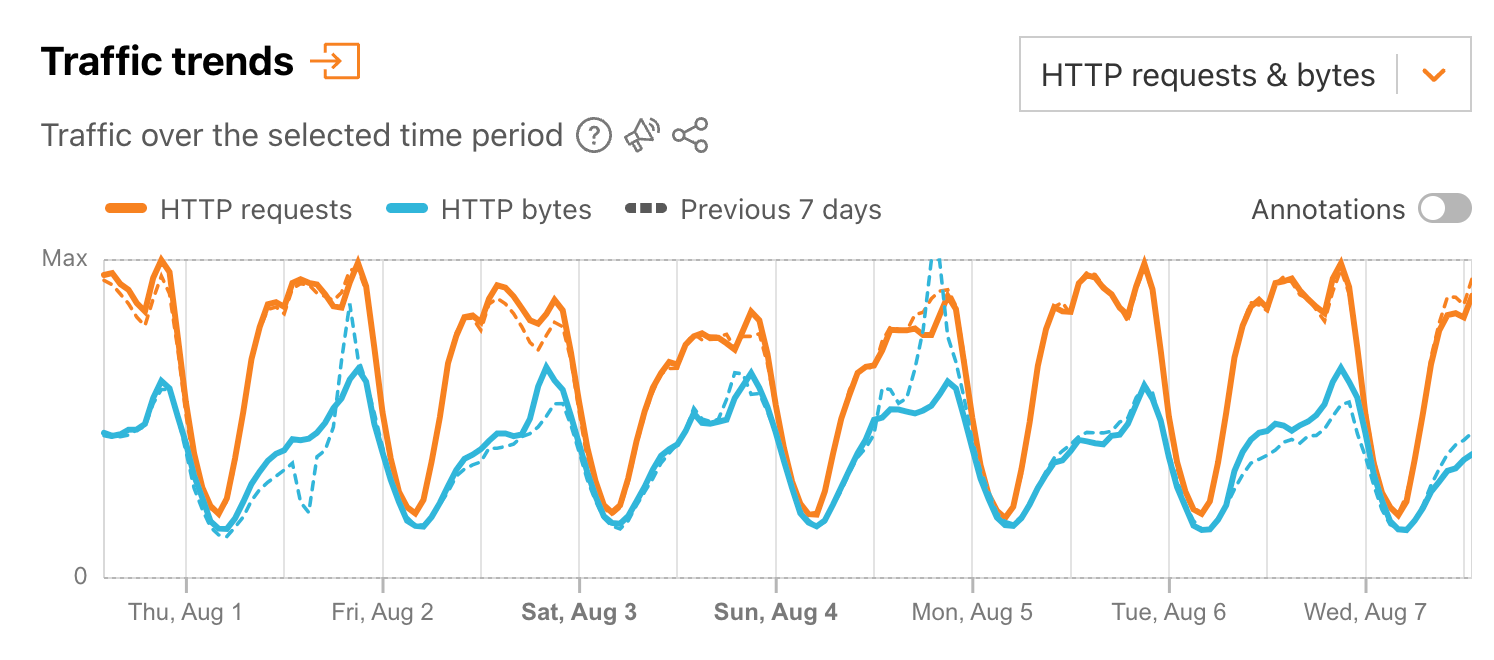
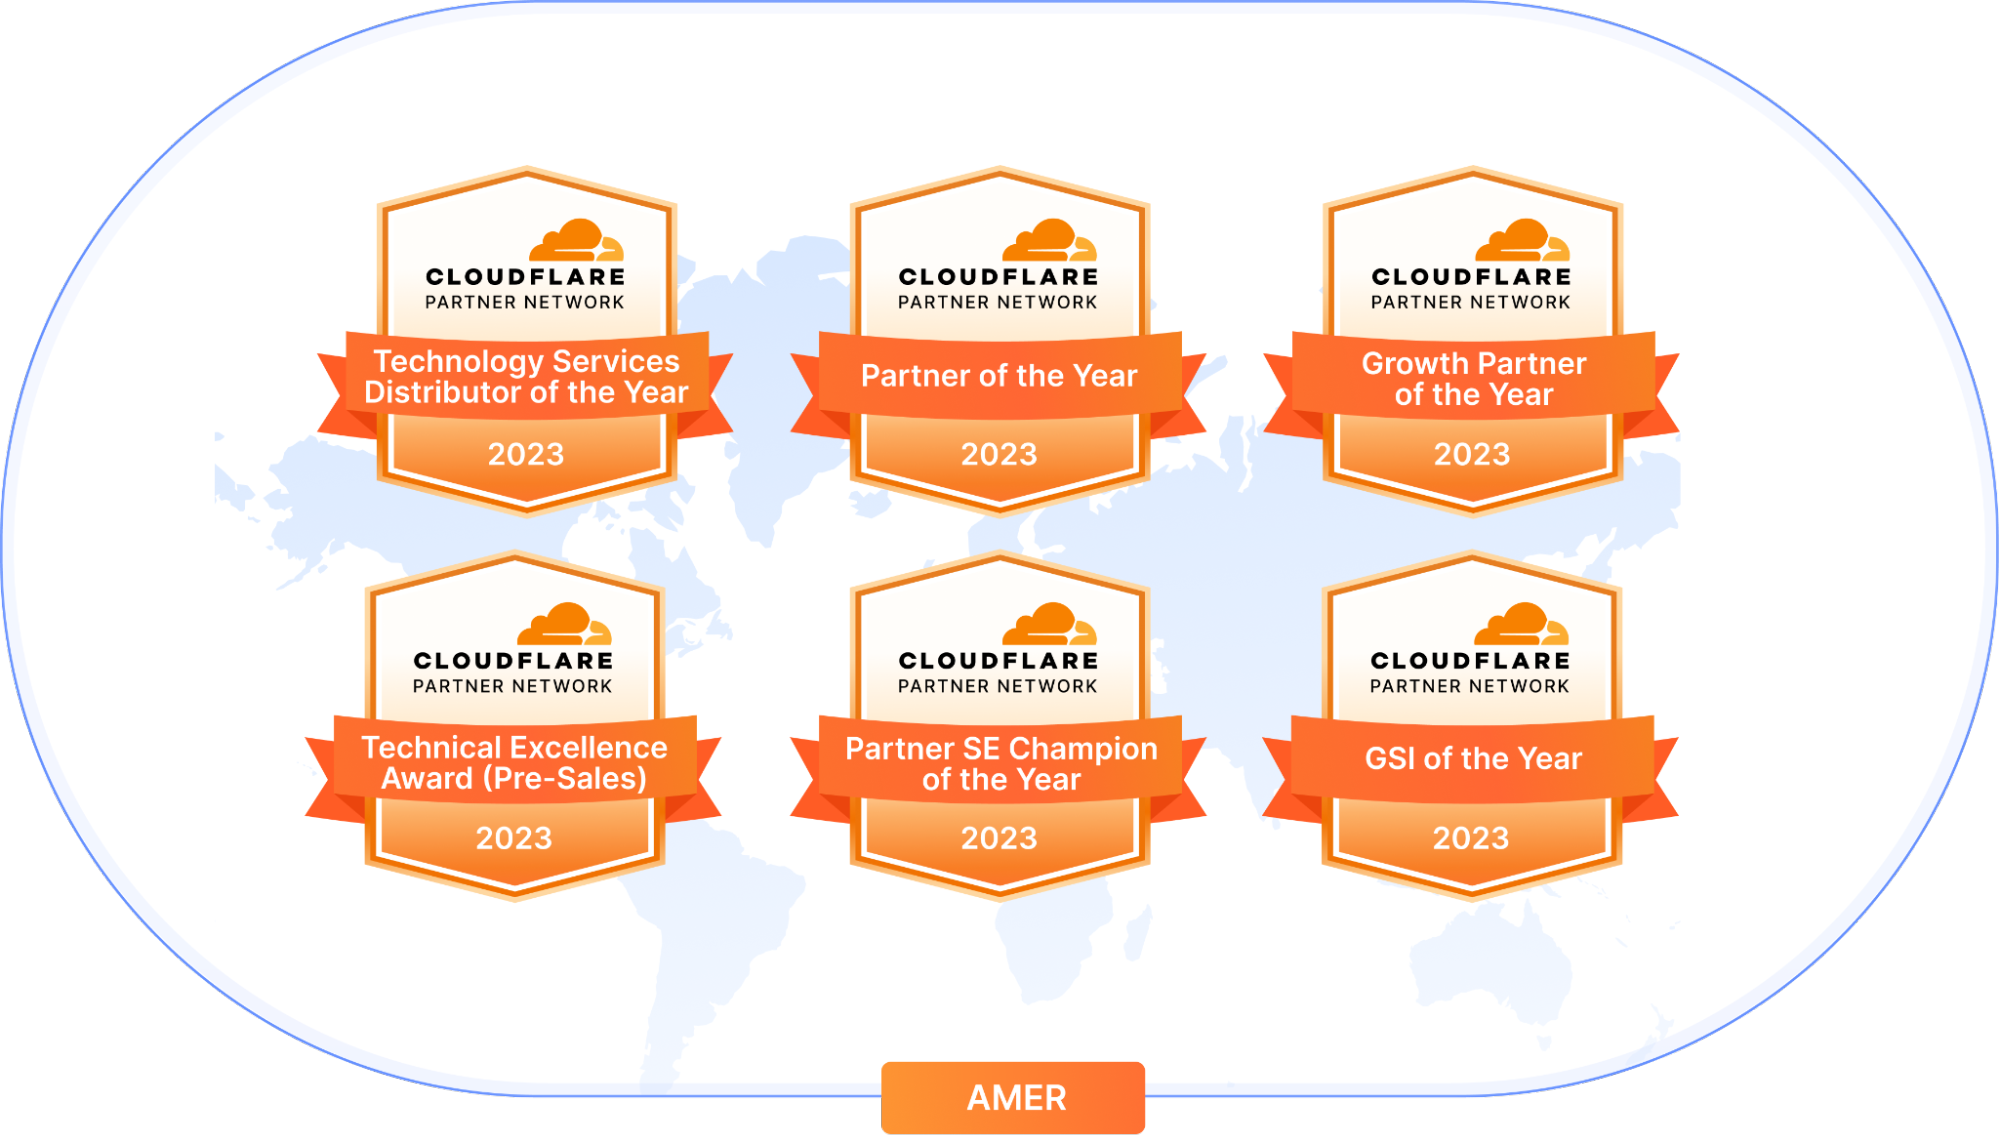
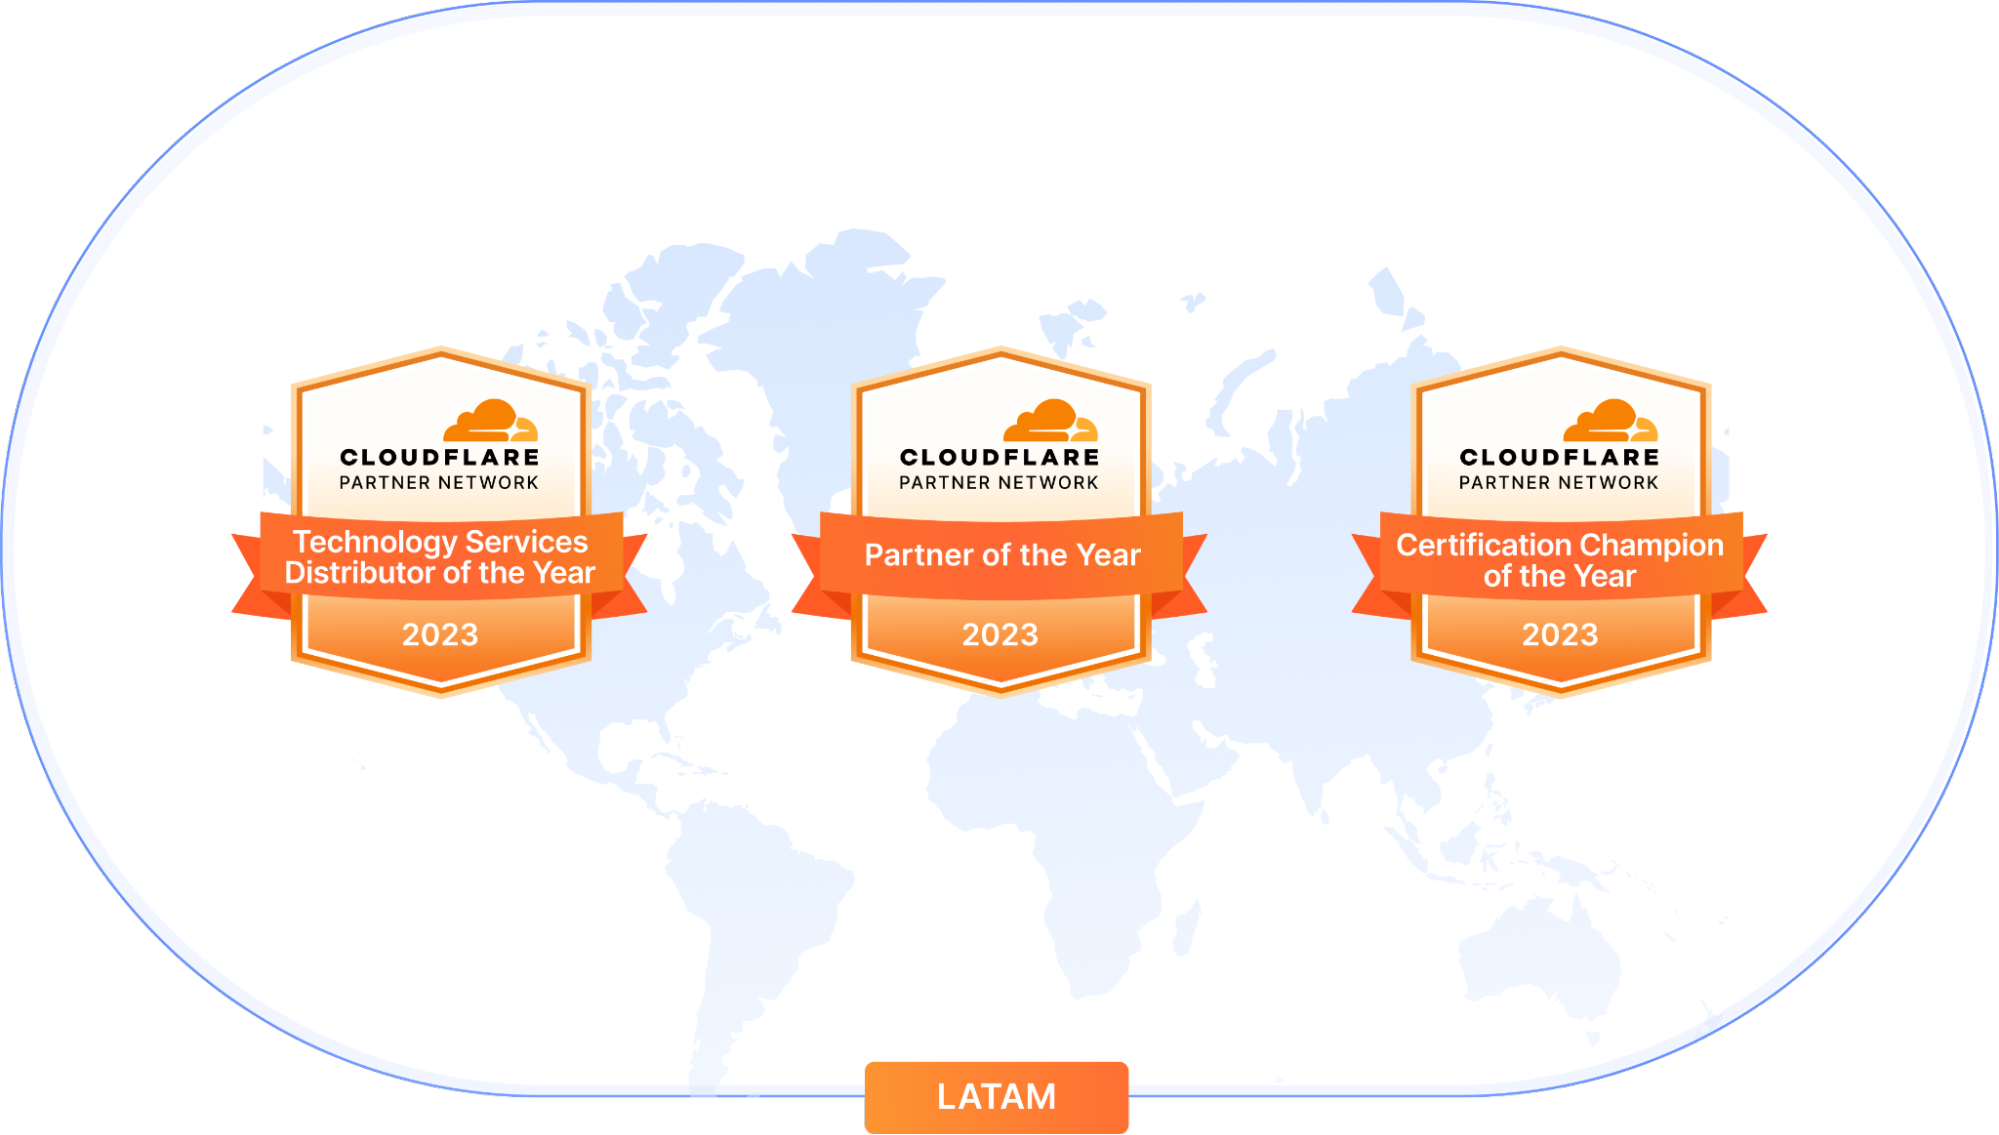
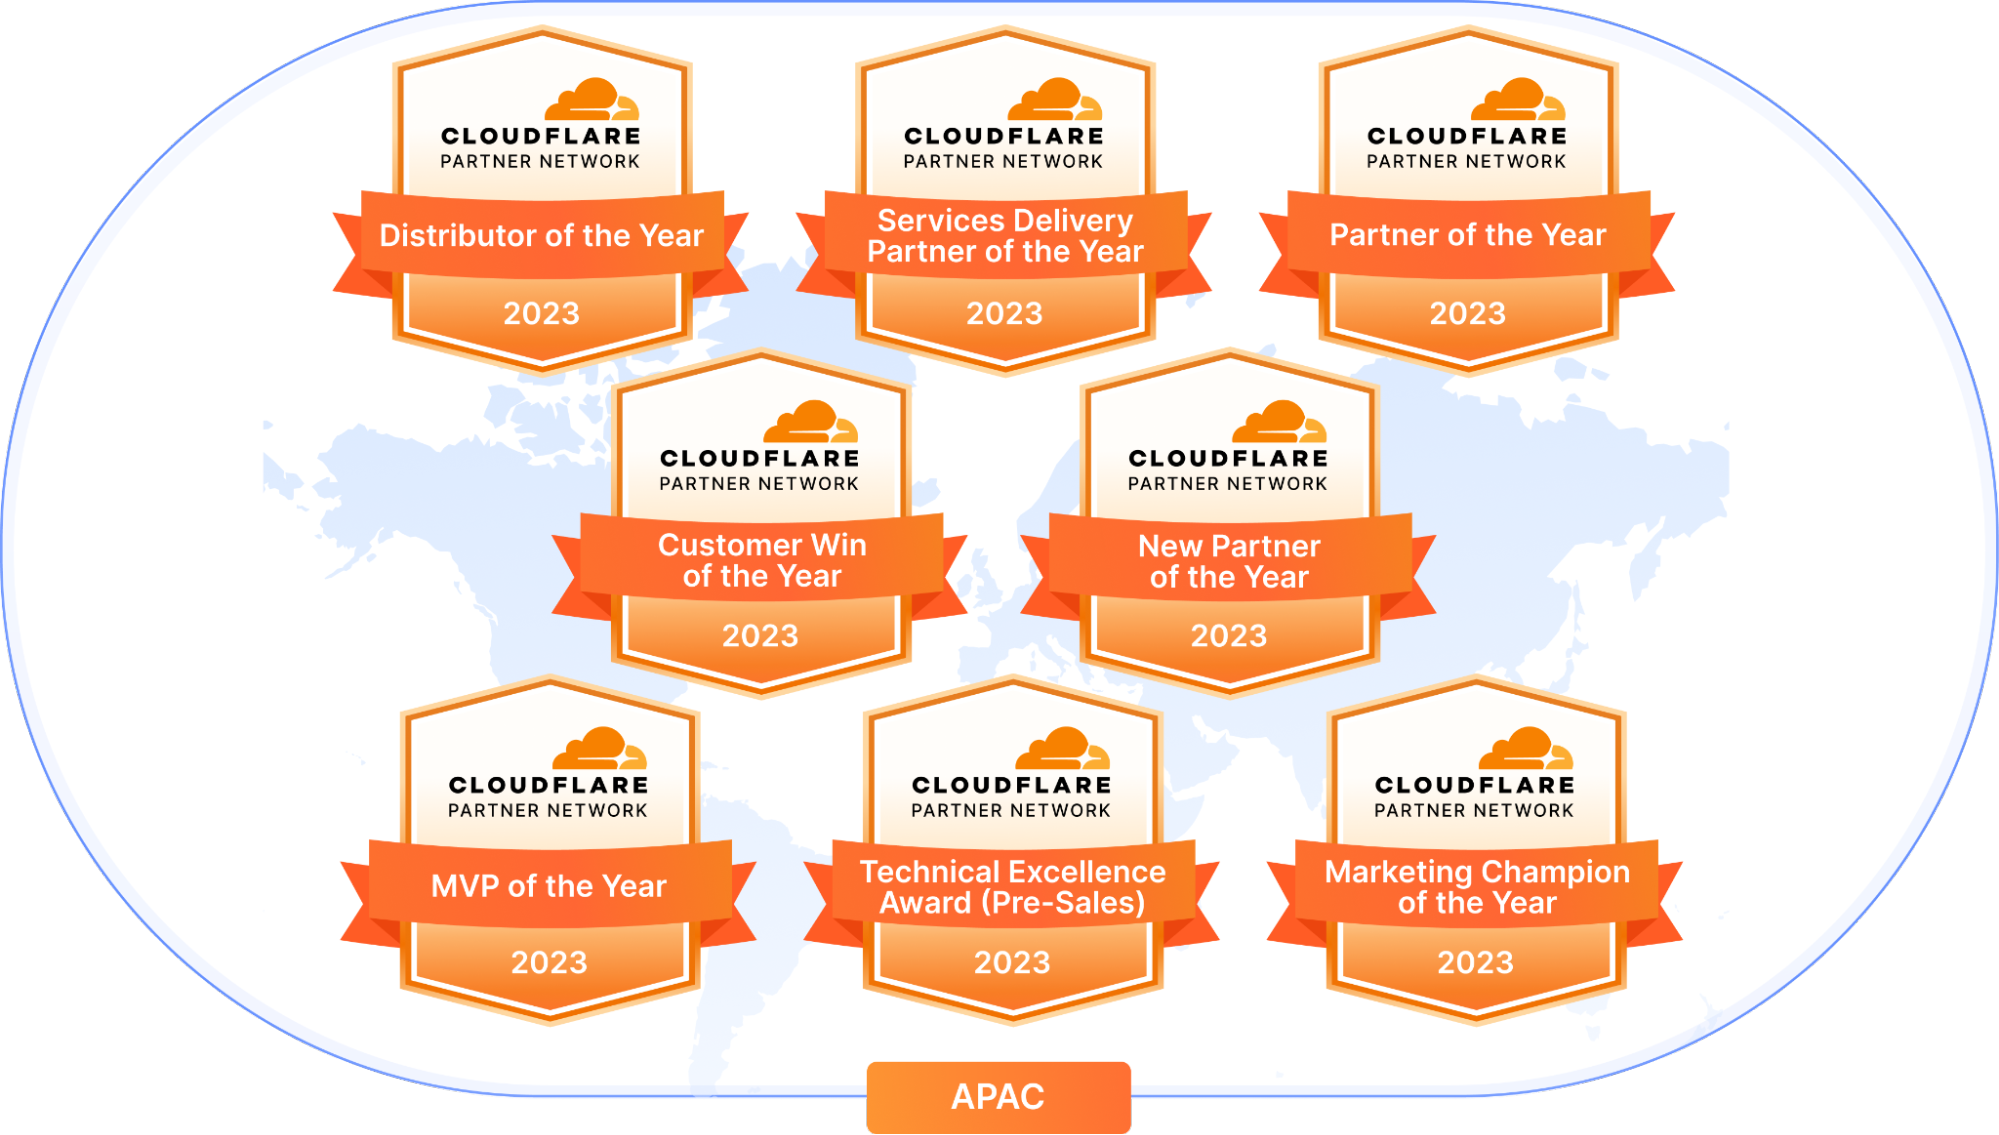
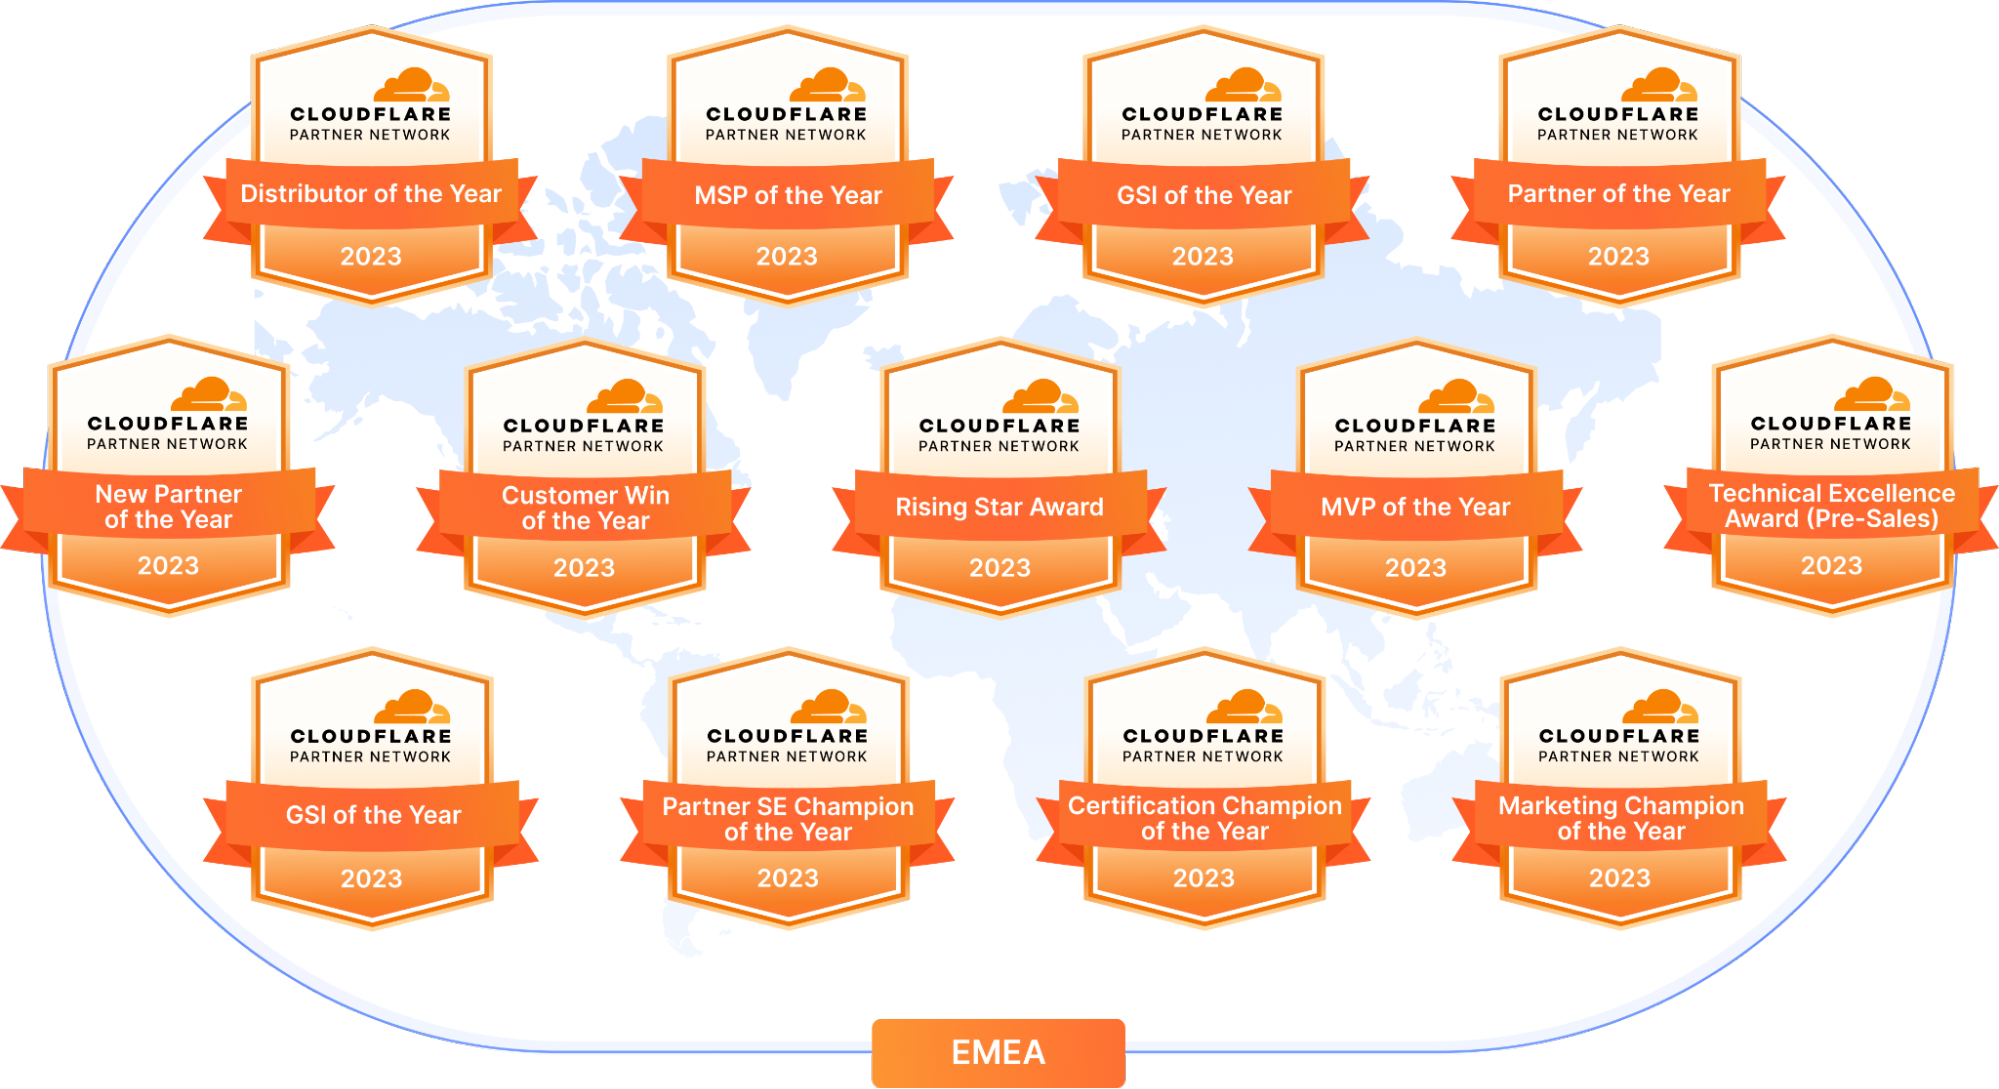


 Ranjan Burman is an Analytics Specialist Solutions Architect at AWS. He specializes in Amazon Redshift and helps customers build scalable analytical solutions. He has more than 16 years of experience in different database and data warehousing technologies. He is passionate about automating and solving customer problems with cloud solutions.
 Vamsi Bhadriraju is a Data Architect at AWS. He works closely with enterprise customers to build data lakes and analytical applications on the AWS Cloud.
 Sumant Nemmani is a Senior Technical Product Manager at AWS. He is focused on helping customers of Amazon Redshift benefit from features that use machine learning and intelligent mechanisms to enable the service to self-tune and optimize itself, ensuring Redshift remains price-performant as they scale their usage.

 For example, for customer-obsessed security, we build and use Mithra, a powerful neural network model to detect and respond to cyber threats. It analyzes up to 200 trillion internet domain requests daily from the AWS global network, identifying an average of 182,000 new malicious domains with remarkable accuracy. Mithra is just one example of how AWS uses global scale, advanced artificial intelligence and machine learning (AI/ML) technology, and constant innovation to lead the way in cloud security, making the internet safer for everyone. To learn more, visit the blog post of Chief Information Security Officer at Amazon CJ Moses,
