Post Syndicated from xkcd.com original https://xkcd.com/3286/
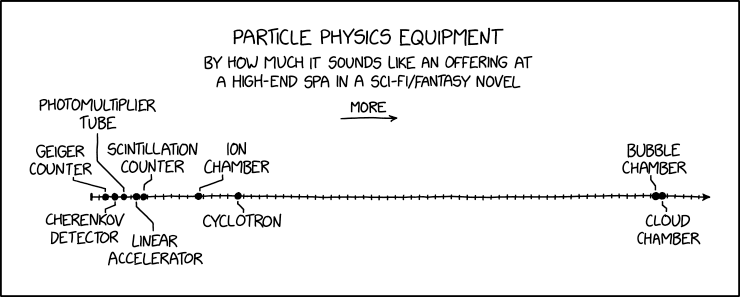
Post Syndicated from xkcd.com original https://xkcd.com/3286/
Post Syndicated from corbet original https://lwn.net/Articles/1088991/
The 7.2 kernel has been released.
Linus said:
Well, this last week of the release was – once again – bigger than
I would have wished for, but hey, with the whole “new normal”
thing, if I delayed releases for that reason we’d probably never
have a release at all.
Significant features in this release include
common
attributes support in the bpf() system call,
cache-aware load balancing for the CPU
scheduler,
large-folio support in the Btrfs filesystem,
further swap subsystem improvements,
improvements to the Landlock security module,
support for block devices with inline encryption hardware via the dm-inlinecrypt
device-mapper target, and much more.
See the LWN merge window summaries
(part 1, part 2) and the KernelNewbies 7.2 page
for more information.
Post Syndicated from Eric Smith original https://www.servethehome.com/adt-r27a-bk3-edsff-e1-s-and-e3-s-to-pcie-slot-review/
We tested the ADT R27A-BK3 which allows you to mount a PCIe Gen5 E1.S or E3.S EDSFF SSD into a PCIe card slot
The post ADT R27A-BK3 EDSFF E1.S and E3.S to PCIe Slot Review appeared first on ServeTheHome.
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=0y91DFVClQ8
Post Syndicated from Bozho original https://techblog.bozho.net/age-verification-is-a-bad-way-to-solve-the-problem-of-children-on-social-networks-whats-the-alternative/
Age verification for using social networks is an idea that is gaining traction in multiple countries around the world – it started in Australia, then the UK, and currently sees increasing support in France and other EU countries, as well as in the European Commission. The idea sounds simple – “social networks are proven to be detrimental to children’s mental health, and so they must not be allowed to use it. The way to do it is to add an age check before registration, so that only adults can use the service”.
While simple to formulate, it’s much more difficult to implement, if not impossible.
First, let’s be clear that I agree 100% that social networks, with their addictive design, their lack of content curation and mediocre attempts to protect children, are bad for minors. And policy makers, such as myself, as a member of parliament of an EU country, need to address that.
But age verification is hardly the right solution, as it’s problematic in many ways which I’ll try to describe here.
“Age tokens” and “age attestations” have been discussed and even implemented. The EU even created a privacy-preserving app, with zero-knowledge prove, that proves the someone is above 18 without them disclosing any identity data (even their age) to the relying party (e.g. a social network). This, however, has problems with circumvention, which I’ll address in the 2nd point. The problem is that fully privacy-preserving solutions are going to be circumvented. If privacy is compromised – i.e. if the solution leaks identifiable information to service providers, age verification becomes “mandatory digital identity for everyone”. I’m a proponent for digital identity for a long time, but strictly optional and mostly for government services, no as a permission to use the internet.
The French law was this weak blocked by the French Constitutional court based on privacy issues. And UK age verification examples have shown some disasters – e.g. one age verification company was found vulnerable and it became obvious that they don’t just check your age – they check you against multiple registers and lists, including for terrorism – which is logical if you want to use every opportunity to reduce risks, but that’s not “on the brochure”.
But privacy-preserving age verification is possible and that’s why we have to address this very seriously. The EU has made a well-meaning attempt to design and implement a proper zero-knowledge proof of age. It’s a great tool, with proper cryptography, complex-yet-elegant. It has “just” one problem – it didn’t account for the actual “threat actor” in this scenario – the user, who would try many things to circumvent the age limitation. As security consultant Paul Moore has brilliantly shown, you don’t have to compromise the age verification app in order to circumvent the flow – by a simple relay attack, where you just present someone else’s verified age credentials in order to use a service. The proof of concept was implemented as a chrome extension which relays age checks to 3rd party service, backed by an over-18 person’s device, which sends the proof to the service. That way a single adult can verify the accounts of all minors, and because of the necessary privacy guarantees, the relying party (the social network) won’t even know.
This is very likely to happen, which “age verification as a service” providers pop-up to help minors get into social networks. What’s worse – some of these providers may collect children’s personal data, including phone number or social network account ID, in order to provide them with the much coveted proof of age. That data, purposefully or after an inevitable data breach, may be used by sex predators to target children. There are completely realistic nightmare scenarios, born from the good intention to limit the negative effects of social networks.
Even in a school context, a single over-18 (or over-16) student can lend their age verification app to help younger children register profiles. What are policy makers going to do then? Issue administrative fines for sharing age tokens/attestations? Criminilize it? It’s obviously the wrong path.
There is one option that may improve this approach, but doesn’t fix it – binding the age attestation to a device ID, so that one device (physical or virtual) can have only one account. That, however, breaks the privacy guarantees – yes, it’s not a personal identifier, but a device identifier, but nevertheless, it allows linking and leaking. And may still be circumvented – with per-request virtual device creation, which would require rate-limiting of attribute providers functionality to attest age. So, broken privacy guarantees and further technical complication that are also likely to be circumvented when someone thinks about it for more than 2 days.
There seems to be a fundamental mismatch between “perfect privacy” and “age verification” (as shown by Paul Moore as well), because if you achieve sufficient privacy guarnantees (like the one in the EU app), a relay attack makes the whole approach useless. And if you ignore or weaken privacy, the whole measure becomes much more problematic.
Obviously, “showing your ID card to the cashier” is not as trivial in the digital world as it is in the physical world. That already leads to a backlach, and policy makers should be aware of those limitations.
The title of this post ends with a question – what’s the alternative? My proposal has two components:
Certain apps can be banned for under-14, others for under-16 and others – for under-18. Governments would be much better control over the exact services they deem risky for children, without the need for any changes on the service’s side. Or, if an app vendor wants to have it whitelisted, they may have to implement children-friendly versions.
Going further, this may eventually lead to platform-level parental control APIs, so that each app can read parental control settings, and on the other hand export parental control configuration options to be used in the parental control app.
This approach is much better from political point of view – it’s not that government that decides – it’s the parent, but with guidance from the government, which provides reasonable defaults, which the parent can override.
These controls are much harder to circumvent – you can’t VPN out of an OS-level ban or an OS-level firewall which blocks outgoing connections, regardless of which your ISP is. It’s completely privacy-preserving, as users don’t have to show or prove anything.
Of course, the harder part is making sure every child and parent has a parental control app installed. Information campaigns and teachers can help with that, and I’m sure it will achieve much better results than what we are seeing in Australia for example.
Children protection agencies can even receive statistics for the number of changed preferences, to monitor for trends of parents just giving up and allowing whatever app the child wants. That’s why the first point in the above proposal is important – limit the addictiveness and brainrot on these platforms as a general rule, not just as a measure to protect children.
The problem is real, The Anxious Generation is spot in, and this mental health pandemic can have devastating long-term effects. That’s why we have to make the best possible decision on how to address it.
The post Age Verification Is A Bad Way To Solve The Problem of Children on Social Networks. What’s The Alternative? appeared first on Bozho's tech blog.
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/freebird/

Post Syndicated from Sam Sabinash original https://www.servethehome.com/kyy-x90d-triple-portable-monitor-review/
Taking two 15.6″ IPS monitors with you and only one cable to surround your laptop is a huge productivity boost as we found in our KYY X90D review
The post KYY X90D “Triple” Portable Monitor Review appeared first on ServeTheHome.
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=7WRG9UVcGgU
Post Syndicated from Jonathan Tuliani original https://aws.amazon.com/blogs/compute/introducing-public-preview-runtimes-on-aws-lambda-starting-with-node-js-26-and-python-3-15/
Today, AWS Lambda introduces public preview runtimes, a new way to try upcoming language versions on Lambda before their general availability (GA) release. Starting today, you can create and update Lambda functions using Node.js 26 and Python 3.15, the first runtimes available as public previews.
Previously, Lambda has always launched new runtimes as Generally Available (GA), giving you a production-ready experience from day one. But this means you couldn’t run your functions on Lambda using a pre-release language version, and we couldn’t hear your feedback while breaking changes were still possible. Public preview runtimes change that. By putting pre-GA runtimes in your hands months earlier, we can listen to your feedback and address it before GA, while we still have the opportunity to make breaking changes to improve the runtime.
Preview runtimes are available in all AWS commercial Regions, AWS GovCloud (US) Regions, and China Regions. They use the same runtime identifier as the eventual GA runtime, so your functions graduate automatically when the runtime reaches GA, with no action required.
When Lambda launches a new runtime as GA, that means it is ready for use in production workloads from day one. Historically, the Lambda team has validated new runtimes through internal testing and pre-release benchmarking. However, without real customer workloads running on the runtime, some issues only surface after the GA launch. And once the runtime is GA, the scope to address those issues is much reduced since we cannot risk breaking existing production workloads.
Public preview runtimes address this by opening up a pre-GA feedback window. During this period, you can deploy functions using the upcoming runtime, and the Lambda team can act on what you find, including making potentially breaking changes if necessary. In addition, because the upstream language is still in its pre-release phase, there’s also the opportunity that issues discovered during preview can be fixed in the runtime itself, not just worked around.
This benefits everyone involved. You get a runtime that’s been tested against a broader range of real workloads before it reaches GA. Third-party partners, including observability providers, infrastructure-as-code tools, and deployment frameworks, get time to validate compatibility. And upstream language communities get a signal from a major cloud platform while they can still act on it.
This is the first time we’re launching runtimes as public previews. As such, it’s an experiment. We hope to make public previews the default for all future runtime launches, depending on the success of this experiment and the feedback we receive.
The Node.js 26 and Python 3.15 preview runtimes are built on the latest upstream pre-release of each language version. At launch, they are a straightforward version bump. There are no additional Lambda-specific enhancements beyond what the new language version itself provides. For details on what’s new in each language version, refer to the upstream release information:
Preview runtimes are available as both managed runtimes and base container images. The base images are published to the Lambda base image ECR repository with image tags starting with 3.15-preview (for Python) and 26-preview (for Node.js).
During the preview period, we may introduce additional features or enhancements to these runtimes. When we do, we’ll announce them on the same GitHub issue we use to collect your feedback:
Follow these issues to stay informed of any changes during the preview period.
Preview runtimes follow the same patching cadence as GA runtimes. When an update is released upstream, Lambda applies it to the preview runtime on the same schedule as any other supported runtime. All Lambda features supported by the current GA runtimes are available on the preview runtimes, including Lambda Managed Instances and durable functions.
The key difference is that the underlying language version has not yet reached its stable release. In addition, the Lambda team is still working on the runtimes to add features and optimize performance. This means breaking changes may occur during the preview period. A function that works today may require a fix after Lambda rolls out the next runtime update. This is by design: the preview period exists so that these issues can be found and resolved before GA, not after.
Because of this potential for breaking changes, preview runtimes are not covered by the AWS Lambda SLA or AWS technical support plans. We strongly recommend against using them for production workloads. Lambda emits a warning message to CloudWatch Logs on each cold start to make it clear when a function is running on a preview runtime:
You may notice that, at launch, preview runtimes have slower performance than GA runtimes, in particular for cold starts. This is because of a combination of lack of optimization and less caching in internal Lambda sub-systems. We will benchmark and optimize performance during the preview period, prior to GA.
Functions that use preview runtimes are billed at standard Lambda rates. There is no additional cost or separate pricing.
We want to hear from you during the preview period. We’ve created a dedicated GitHub issue for each preview runtime where you can share your experience:
Comment on these issues directly, or open a separate issue in the repository if you prefer.
We’re interested in all feedback, not just bug reports. If you see an opportunity to take advantage of a new language feature in the runtime, or a way to improve the Lambda programming model for that language, we want to hear about it. The preview period is when we can still make meaningful changes, so this is the best time to share your ideas.
Note that feedback should be scoped to the runtime itself: the execution environment, language integration, and programming model. For broader Lambda feature requests, refer to the AWS Lambda public roadmap.
Both Node.js 26 and Python 3.15 are expected to reach their stable upstream releases in October 2026. Lambda GA for each runtime is targeted within two months following those releases. For the latest estimated GA dates, see Lambda documentation.
For Node.js, the GA timeline is tied to the Node.js “Active LTS” release, which is scheduled for October 2026. Only at that point is the release considered suitable for production workloads by the Node.js project, and only then is it sufficiently stable for Lambda’s automatic runtime patching in which patches are applied to your functions without action on your part. Lambda will not GA the Node.js 26 runtime until it reaches Active LTS.
When a preview runtime reaches GA, your functions graduate automatically. The runtime identifier does not change: nodejs26.x in preview is the same nodejs26.x at GA. You do not need to update your function configuration, templates, or code. The preview label is removed from the console and documentation, the runtime becomes covered by the Lambda SLA and AWS Support, and the GA performance and quality bar applies from that point forward.
If you have pinned your function to a specific runtime version using Runtime Management Controls during the preview period, it remains pinned. You can unpin at any time to move to the GA runtime. Functions pinned to a pre-GA runtime version are not covered by the Lambda SLA and AWS Support.
You can start using the Node.js 26 and Python 3.15 preview runtimes today using the Lambda console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, AWS Serverless Application Model (AWS SAM), or AWS Cloud Development Kit (AWS CDK).
In the Lambda console, choose “Node.js 26 (Preview)” or “Python 3.15 (Preview)” from the runtime list when creating or updating a function.
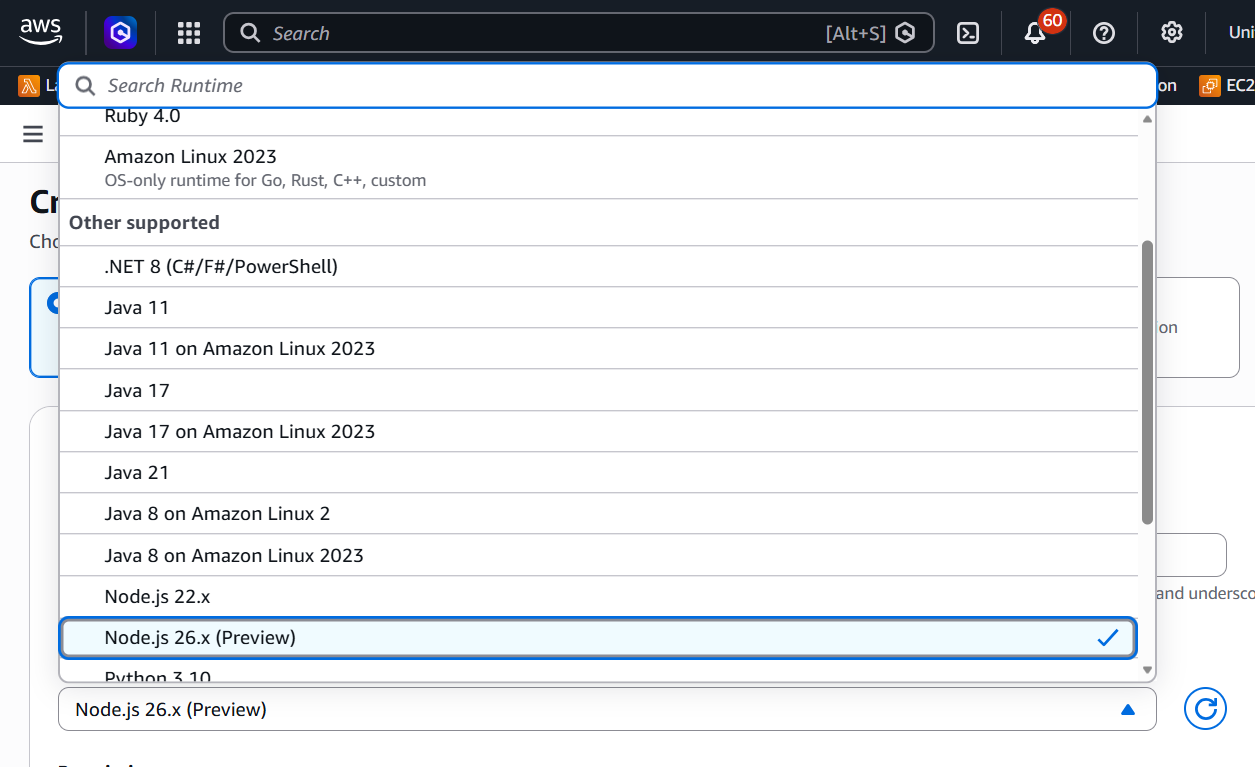
Create a function using the preview runtime with the standard runtime identifier:
For Python 3.15, use --runtime python3.15. These are the same identifiers the GA runtimes will use, there is no separate preview-specific value.
Specify the preview runtime in your CloudFormation template using the same runtime identifier:
AWS SAM supports preview runtimes using the standard runtime identifier in your template:
When you run sam init, preview runtimes appear in the template list with a “(Preview)” label, so you can scaffold a new project directly.
The AWS CDK does not yet include built-in enum members (such as Runtime.NODEJS_26_X). During the preview phase, you can use the public Runtime constructor to specify the runtime directly, for example:
Or, for Python 3.15, replace new Runtime("nodejs26.x", RuntimeFamily.NODEJS) with new Runtime("python3.15", RuntimeFamily.PYTHON).
This synthesizes identical CloudFormation to what a built-in enum produces. When the runtime reaches GA, a corresponding enum member will be added. There is no functional difference in the meantime.
Public preview runtimes give you a seat at the table while Lambda’s next runtimes are still taking shape. Try using Node.js 26 or Python 3.15 today to deploy a function, run your test suite, and let us know what you find.
Share feedback and follow along:
These GitHub issues are where we’ll post any enhancements or breaking changes during the preview period, so they’re worth watching even if you don’t have immediate feedback. The preview runtimes are available today in all AWS Regions, including AWS GovCloud (US), and the AWS China Regions. To learn more, see the Lambda runtimes documentation.
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=3H3QRtDTE4Y
Post Syndicated from Rapid7 Labs original https://www.rapid7.com/blog/post/pt-metasploit-wrap-up-lot-of-summer-shells-and-fit-http-profiles
This wrap-up brings a full-on shell parade. Thirteen shiny new modules landed, starting with a buffet of RCEs. WordPress WP2Shell, Ghost CMS, Joomla JCE, Langflow, OpenCATS, Pterodactyl Panel, SonicWall SMA1000, Ray Dashboard, a Pix-for-WooCommerce, and for those who like their exploits closer to the bare-metal, the Fragnesia Linux kernel LPE (CVE-2026-46300). Metasploit also got the glow-up of the summer with the new http malleable profiles, MCP functionality and linux multi fetch payloads (more details on the [official 6.5 release blog post](https://www.rapid7.com/blog/post/pt-metasploit-framework-6-5-released/)!). Windows on ARM confirm to be the new first-class citizenship thanks to brand-new AArch64 reverse-TCP shells (both inline and staged), so your Snapdragon boxes can join the party too. Last but not least, an important message: *Nyan Nyan Nyan Nyan Nyan Nyan.*
Author: Richard Howe <rhowe425>
Type: Auxiliary
Pull request: #21681 contributed by rmhowe425
Path: `gather/ray_dashboard_logs_api_path_traversal`
Description: This adds an auxiliary module that leverages a path traversal vulnerability in Ray to list the contents of local directories. There is currently no CVE assigned to this vulnerability. Issuance is pending with MITRE.
Authors: 0xtensho and jheysel-r7
Type: Exploit
Pull request: #21452 contributed by jheysel-r7
Path: `linux/http/pterodactyl_locales_locale_json`
AttackerKB reference: CVE-2025-49132
Description: This adds a module which exploits a vulnerability in Pterodactyl Panel before version 1.11.11 that allows unauthenticated remote code execution through improper handling of locale file operations. The vulnerability, CVE-2025-49132, exists in the locale.json endpoint which allows path traversal and arbitrary file creation. This combination of capabilities results in remote code execution in the context of the user running the web server.
Authors: Deral Heiland, Rapid7 Vulnerability Research, and Ryan Emmons
Type: Exploit
Pull request: #21678 contributed by dheiland-r7(https://github.com/dheiland-r7)
Path: `linux/http/sonicwall_sma1000_wsproxy_rce`
AttackerKB reference: CVE-2026-15409
Description: This adds a new exploit module for CVE-2026-15409, a Server-Side Request Forgery (SSRF) vulnerability in the SonicWall SMA1000 WorkPlace wsproxy service.
Authors: William Bowling and msutovsky-r7
Type: Exploit
Pull request: #21456 contributed by msutovsky-r7
Path: linux/local/cve_2026_46300_fragnesia
AttackerKB reference: CVE-2026-46300
Description: This adds a local module for the Fragnesia exploit which is a page-cache replacement vulnerability in the Linux kernel’s XFRM (IPsec) subsystem, tracked as CVE-2026-46300.
Authors: Cristian-Alexandru Staicu and Maksim Rogov
Type: Exploit
Pull request: #21234 contributed by vognik
Path: multi/http/ghostcms_auth_rce_cve_2026_29053
AttackerKB reference: CVE-2026-22594
Description: This adds an exploit module for Ghost CMS (CVE-2026-29053) that achieves remote code execution by uploading a malicious theme. Ghost’s theme renderer evaluates untrusted JSONPath expressions through the {{#get}} helper, letting the module inject and trigger arbitrary code once a theme is uploaded and activated. You’ll need valid admin or staff credentials to authenticate.
Authors: David Jardin, Uwe Flottemesch, and ispyispyispy
Type: Exploit
Pull request: #21615 contributed by 15py15py15py
Path: multi/http/joomla_com_jce_unauth_file_upload_rce
AttackerKB reference: CVE-2026-48907
Description: This adds a new exploit module for CVE-2026-48907, an unauthenticated arbitrary profile creation vulnerability in the JCE (Joomla Content Editor) extension for Joomla!. The profiles.import task fails to enforce authentication, letting an attacker import a crafted profile that is written to disk as a PHP web shell, resulting in remote code execution when the tmp/ directory is directly accessible. All JCE versions up to and including 2.9.99.4 are affected, and no credentials are required.
Authors: Diamorphine and Richard Howe
Type: Exploit
Pull request: #21700 contributed by rmhowe425
Path: multi/http/langflow_unauth_rce_cve_2026_33017
AttackerKB reference: CVE-2026-33017
Description: Adds a new multi/http/langflow_unauth_rce_cve_2026_33017 exploit module that exploits an unauth RCE vulnerability in the /api/v1/build_public_tmp/{flow_id}/flow endpoint in Langflow versions prior to 1.9.0.
Authors: Chocapikk and stlthr4k3r
Type: Exploit
Pull request: #21630 contributed by stlthr4k3r
Path: multi/http/opencats_installer_rce
AttackerKB reference: CVE-2026-27760
Description: Adds an exploit module targeting CVE-2026-27760, a PHP code injection in OpenCATS.
Authors: Adam Kues, Crypto-Cat, TF1T, dtro, and haongo
Type: Exploit
Pull request: #21686 contributed by Crypto-Cat
Path: multi/http/wp_batch_desync_rce
AttackerKB reference: CVE-2026-60137
Description: This adds an exploit module to target WP2Shell, an unauthenticated pre-auth remote code execution vulnerability affecting WordPress core versions 6.9.0–6.9.4 and 7.0.0–7.0.1. The module chains a REST API route confusion flaw (CVE-2026-63030) with an SQL injection (CVE-2026-60137) to elevate privileges, deploy a payload via a custom plugin, and execute a remote session.
Authors: Alexis Lafontaine and Maksim Rogov
Type: Exploit
Pull request: #21683 contributed by vognik
Path: multi/http/wp_plugin_pix_unauth_rce_cve_2026_3891
AttackerKB reference: CVE-2026-3891
Description: Adds CVE-2026-3891 WordPress Unauthenticated RCE Exploit module targeting Pix for WooCommerce plugin.
Authors: OJ Reeves, Spencer McIntyre
Type: Payload (Single) Pull request: #21728 contributed by zeroSteiner
Description: Adds support for a new MALLEABLEC2 option to Meterpreter HTTP(S) payloads. This feature enables users to load a standard profile into Meterpreter and change the shape of its HTTP(S) traffic. All Meterpreters, including Windows, Java, Python, PHP and Linux, have been updated with this functionality.
Author: vinicius-batistella
Type: Payload (Single)
Pull request: #21589 contributed by vinicius-batistella
Path: windows/aarch64/shell_reverse_tcp
Description: Adds Windows on ARM (AArch64) reverse-TCP command-shell payload.
Author: vinicius-batistella
Type: Payload (Stager)
Pull request: #21744 contributed by vinicius-batistella
Path: windows/aarch64/shell/reverse_tcp
Description: Adds Windows AARCH64 staged shell payloads.
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest. To install fresh without using git, you can use the open-source-only Nightly Installers or the commercial edition Metasploit Pro.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/friday-squid-blogging-searching-for-the-colossal-squid-2.html
Fascinating video about searching for life undersea. The video basically makes the point that our bright white searchlights are scaring everything away, and that red light is more neutral. That, plus bait to attract sea creatures, is teaching us a lot about what’s going on down there. Lots of footage of giant squid, and speculation about the colossal squid. Worth watching.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Post Syndicated from Eric Smith original https://www.servethehome.com/160-bay-nvme-ssd-4u-server-shown-at-fms-2026-supermicro-asg-4116s-nu160r/
On the FMS 2026 show floor, we saw a massive 160-bay NVMe storage server (Supermicro ASG-4116S-NU160R) that can deliver crazy storage density
The post 160-bay NVMe SSD 4U Server Shown at FMS 2026 Supermicro ASG-4116S-NU160R appeared first on ServeTheHome.
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/ILQQv9dV17s
Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/compute/implementing-dynamic-feature-flags-with-aws-appconfig-on-aws-lambda/
Feature flags (also known as feature toggles) allow you to change application behavior in real time without deploying new code. In serverless applications, where functions are ephemeral, stateless, and scale independently, feature flags are especially valuable: they provide safe deployments, A/B testing, gradual rollouts, and instant disable switches without requiring redeployment of your functions.
Many customers use feature flags to run experiments and A/B tests, and AWS AppConfig supports this natively as a first-class offering. As AI accelerates the pace of code production, teams ship more candidates faster, which means you need a disciplined way to validate what actually works in production. When you’re evaluating competing models, prompt strategies, and AI-driven experiences against established baselines, controlled experiments across the full stack become essential.
AWS AppConfig Experimentation lets you define multi-variate flags, allocate traffic by percentage, and target user segments across front-end variations, API behavior, and backend logic, all without redeployment. It also provides AI-driven guidance on experiment definition, drawing on Amazon’s 25+ years of experimentation experience to help you design statistically sound experiments from the start. Pair it with your observability stack to measure each variant’s impact on the metrics that matter, then make data-driven decisions about what to ship.
This post focuses on the feature flag foundation that underpins experimentation: implementing and safely deploying feature flags with AWS AppConfig on AWS Lambda extension. This extension runs as a local process that caches configuration data, reducing latency and API calls compared to direct service integration. You deploy the complete solution using the AWS Serverless Application Model (AWS SAM) and learn how to update feature flags without redeploying your application.
Lambda functions are ephemeral and stateless. Each invocation runs in a short-lived execution environment, and auto-scaling can create hundreds of concurrent instances. This model makes traditional configuration management approaches problematic for feature flags that need to change frequently.
Common approaches to managing configuration in Lambda functions each have trade-offs:
Each of these approaches either forces a redeployment for every change or pushes caching and synchronization complexity into your application code. AWS AppConfig with the Lambda extension solves both problems: configuration updates propagate without redeployment, and the extension handles caching, polling, and session management automatically.
AWS AppConfig is designed for dynamic configuration management. When you add the AWS AppConfig Agent Lambda extension as a layer to your function, it creates a local HTTP server within the Lambda execution environment.
Here is how the interaction works:
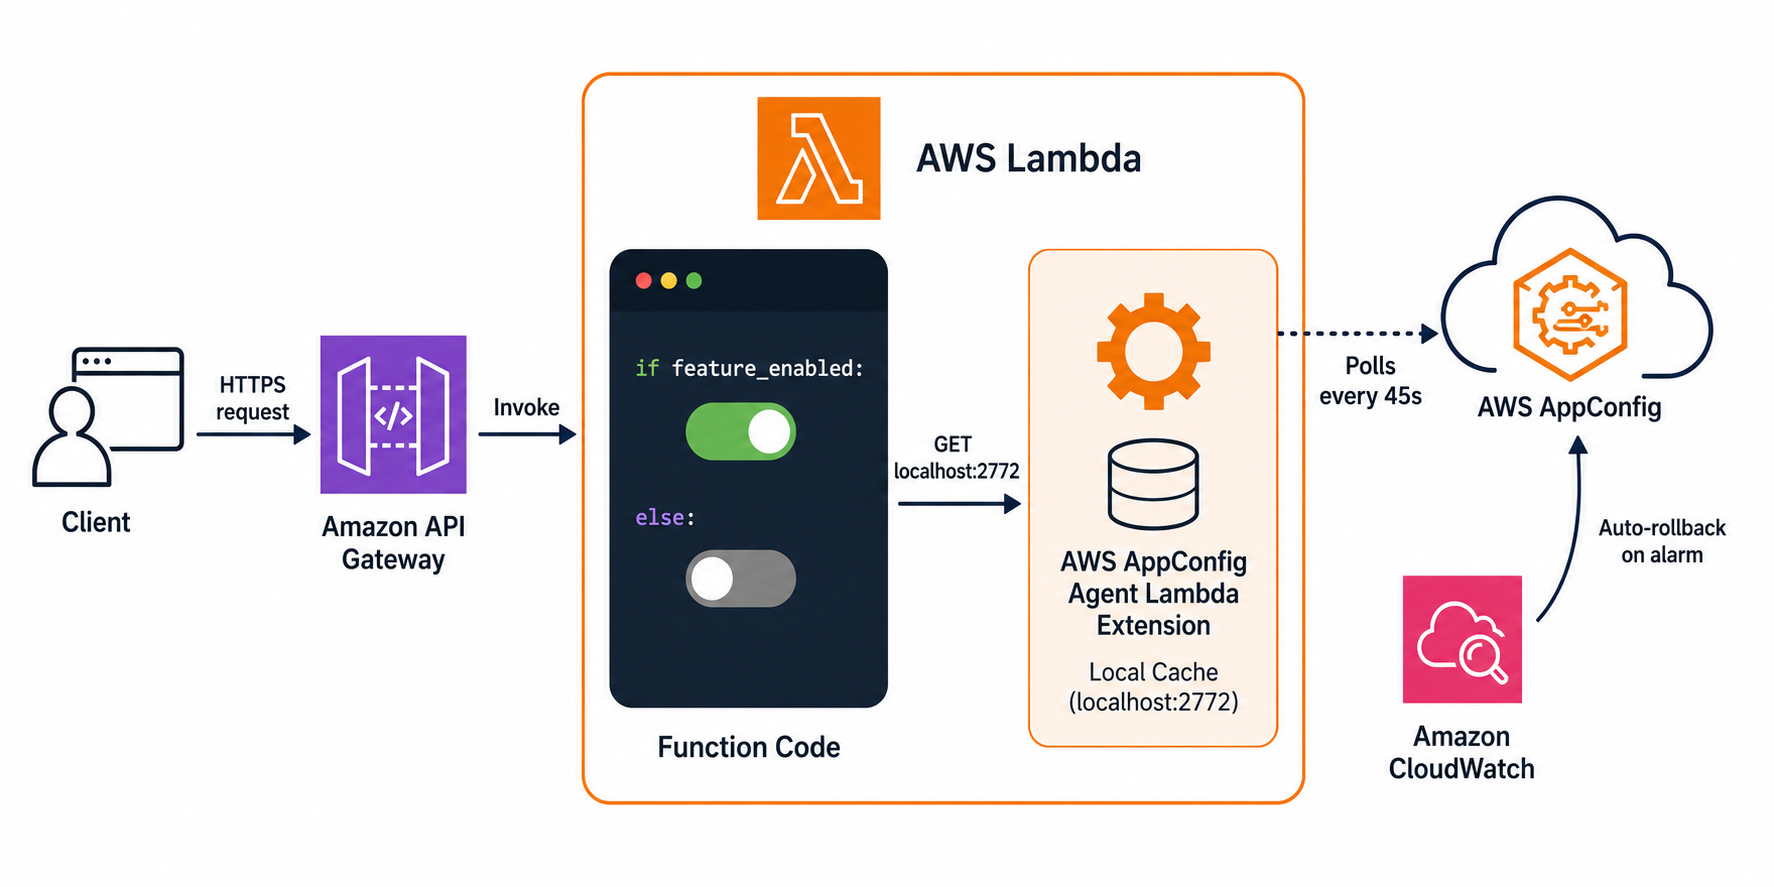
Figure 1 – Architecture overview showing the feature toggle solution with AWS Lambda, AWS AppConfig Agent Extension, and AWS AppConfig.
Init phase, the extension starts and establishes a session with the AWS AppConfig service. It retrieves the current configuration and caches it locally.http://localhost:2772 to read the cached configuration. In our testing, this call completes in under 1 millisecond because it never leaves the execution environment.Figure 2 – Lambda Extensions run as separate processes within the execution environment. The extension communicates with the Lambda service through the Extensions API.
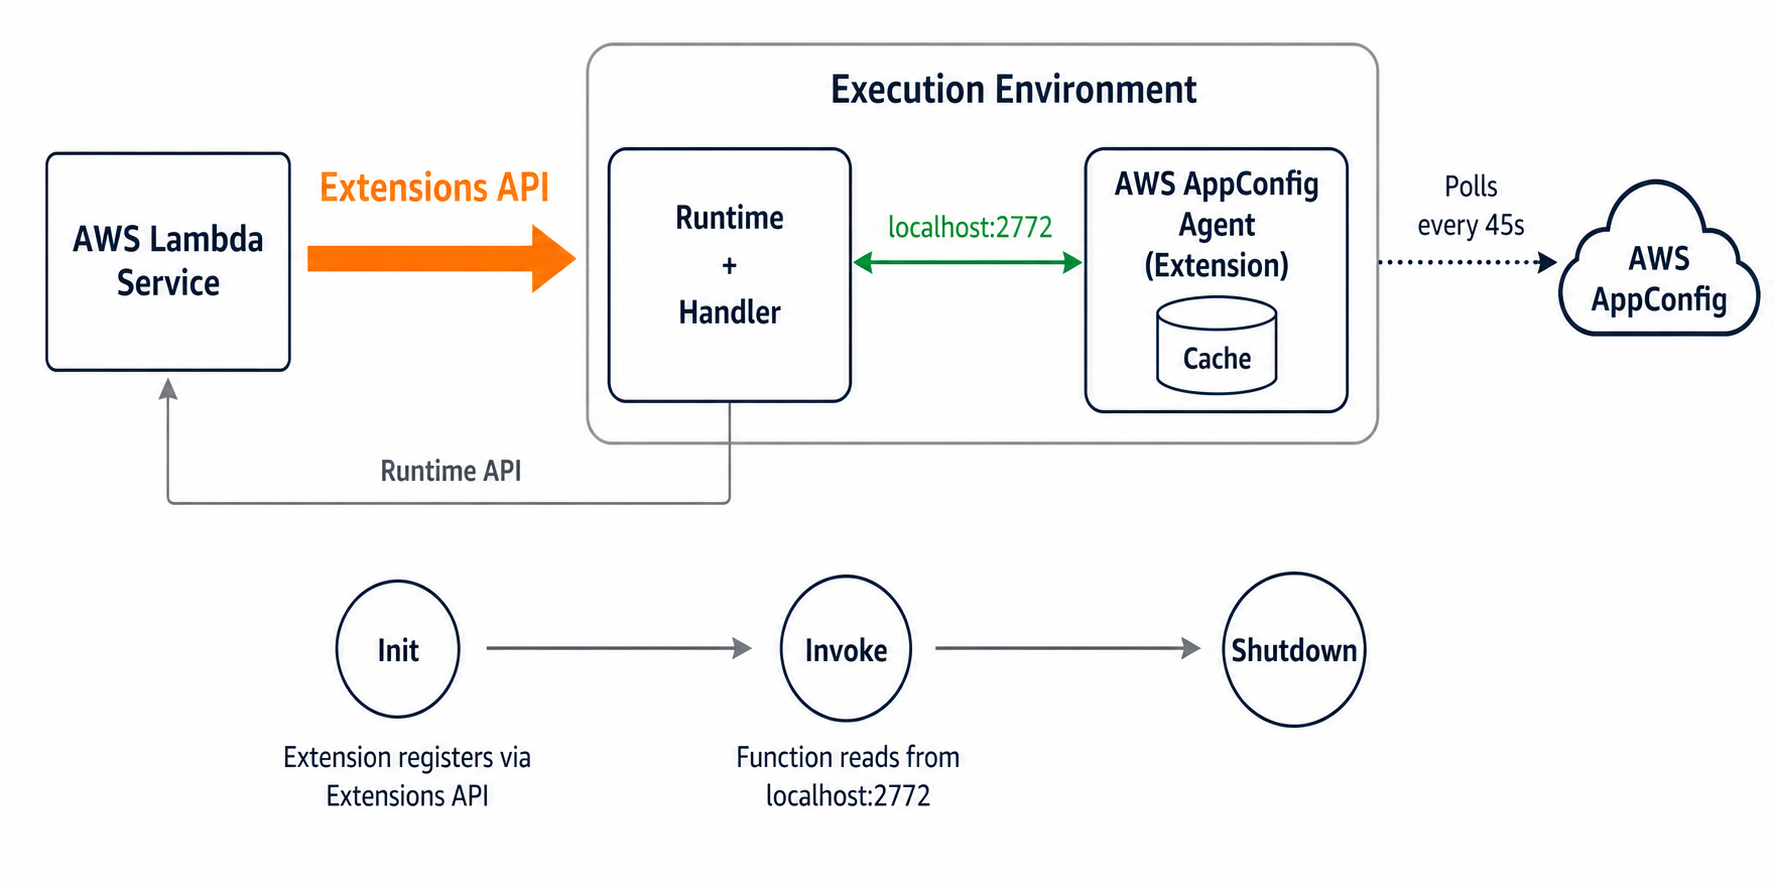
This design provides several advantages over direct API integration:
StartConfigurationSession + GetLatestConfiguration) that count toward your AppConfig usage costs. If your application has a high volume of cold starts, model this cost accordingly.StartConfigurationSession and GetLatestConfiguration calls, token refresh, and retries.To deploy this solution, you need:
Now that you understand how the extension works, let’s look at the infrastructure. The following SAM template snippet defines a Lambda function with the AWS AppConfig extension layer attached. Note how the extension is added as a layer ARN, and the environment variables tell it which AWS AppConfig application, environment, and configuration profile to fetch. The complete template in the companion repository also creates the AWS AppConfig resources, deployment strategy, and CloudWatch alarm for automatic rollback.
Deploy the stack:
SAM creates the Lambda function with the extension layer attached and least-privilege IAM permissions scoped to the specific AWS AppConfig resource ARN.
Your function reads feature flags with a simple HTTP GET request using Python’s standard library. No external dependencies are required:
Notice that the flags drive real execution paths, selecting which algorithm runs, not merely populating a display field. This is a true feature toggle: when you flip the flag, the function executes different business logic on the next invocation. The following example shows a freeform configuration profile (AWS.Freeform type). For production use, consider the AWS.AppConfig.FeatureFlags type instead (see Best Practices below), which provides a console UI for non-technical users and tools for managing flag lifecycle:
One of the most valuable features of AWS AppConfig for production environments is controlled deployments. Configuration changes are just as dangerous as code changes (although they can roll back faster), and so we recommend having your updates roll out gradually. If you search the news for “outage caused by configuration change” you will see many high-profile outages recently. Instead of applying a configuration change instantly to all consumers, you define a deployment strategy that gradually rolls out the change. The following snippet (included in the full template) shows a linear rollout:
This strategy applies the new configuration linearly: 20% of consumers receive the update every 2 minutes over a 10-minute window. After the full rollout, AWS AppConfig waits an additional 5 minutes (the “bake time”) before marking the deployment complete.
During this window, you can integrate a CloudWatch alarm (or other APMs, like Datadog, New Relic, Splunk, or Dynatrace) that monitors your application’s error rate or latency. If the alarm enters ALARM state, AWS AppConfig automatically rolls back to the previous configuration version. The companion repository includes a complete CloudWatch alarm example wired to the deployment.
After your stack is deployed, you can update any feature flag by creating a new configuration version and starting a deployment:
Within the poll interval, all running Lambda instances pick up the new configuration. No code changes, no redeployment, no downtime. Reverting a flag is equally fast and symmetric. Deploying the previous configuration version propagates in the same ~30 seconds, giving you a consistent rollback speed whether you are enabling or disabling a feature. Importantly, the API contract (response structure, status codes, error shapes) remains stable regardless of flag state. Only the behavior behind the toggle changes, so consumers of your API are never broken by a flag flip.
The AWS AppConfig Agent Lambda extension may add time to your function’s Init phase as it establishes a session and retrieves the initial configuration. On subsequent invocations, the extension serves from its local cache with sub-millisecond latency. If your function has a strict cold start target, consider provisioned concurrency for latency-critical paths.
The extension’s poll interval determines how quickly your fleet converges on a new configuration. The template configures 30 seconds (the AWS default is 45 seconds). This interval suits most rollouts. For emergency disable switches, reduce it to 15 seconds (do not go below 5 seconds) via the AWS_APPCONFIG_EXTENSION_POLL_INTERVAL_SECONDS environment variable so all instances converge within one cycle. The extension is also resilient to network failures. If it cannot reach AWS AppConfig, it continues serving the last known good configuration from cache. Your function never fails because of an upstream connectivity issue.
Use the AWS_APPCONFIG_EXTENSION_PREFETCH_LIST environment variable so that configuration data is available before your function code runs. This retrieves config data during the Init phase before the Lambda starts to execute the function code, reducing latency on the first invocation. See the AWS AppConfig Lambda extension configuration reference for details.
Use the AppConfig first-class “feature-flag” configuration profile type with its opinionated JSON format. This data type gives you a simple console experience for non-technical users, advanced multi-variate flags, and tools for cleaning up stale feature flags. Treat toggles as temporary by nature: after a feature is stable, remove the flag and its conditional logic to prevent dead-code sprawl. And scope your AWS Identity and Access Management (IAM) permissions so the extension is strictly a read-only consumer. Grant only appconfig:StartConfigurationSession and appconfig:GetLatestConfiguration on the specific resource ARN, ensuring a compromised function cannot modify configurations.
To avoid ongoing charges, delete the resources you created in this walkthrough. Run the following command from the project directory:
This removes the Lambda function, API Gateway endpoint, and all AWS AppConfig resources created by the template.
The AWS AppConfig Lambda extension provides a lightweight, managed approach to feature flags in serverless applications. The extension handles caching, polling, and session management, while AWS AppConfig provides safe deployment strategies with validation and automatic rollback.
Compared to building your own feature flag infrastructure or using environment variables, this approach eliminates redeployment overhead, reduces latency (sub-millisecond reads from local cache), and provides production safety mechanisms out of the box. Your function code stays simple: a single HTTP GET to a local endpoint.
The pattern shown in this post applies beyond simple boolean flags. You can store complex configuration objects, percentage-based rollout rules, or user-segment targeting data in the same configuration profile. As your feature management needs grow, AWS AppConfig scales with you without requiring changes to the Lambda function integration pattern.
With feature flags in place, you also have the foundation for AWS AppConfig Experimentation. From here you can define multi-variate experiments, allocate traffic to variants, and measure outcomes across your full stack, turning the feature flags you built in this post into a controlled experiment.
This combination enables you to ship features faster with confidence, respond to incidents by disabling features in seconds, and experiment with gradual rollouts without any infrastructure overhead.
You can find the complete source code in the GitHub repository.
If you have questions or feedback about this solution, leave a comment on this post.
For more information, see:
For more serverless learning resources, visit Serverless Land.
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/upcoming-speaking-engagements-59.html
This is a current list of where and when I am scheduled to speak:
The list is maintained on this page.
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=J7GXS7WGgOo
Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/results-from-the-backblaze-generative-ai-media-hackathon/
Between June 22 and August 3, 2026, 1,314 people entered hundreds of projects into a single brief: build a generative media app on Backblaze B2 object storage, orchestrated through the open-source Genblaze SDK, for a share of a $10,000 prize pool.
Almost every entry could generate an image, a video, or a soundtrack, and generate it well. What separated the strongest was the layer underneath: what gets written down, what can be proved later, and what happens when a file has to be checked, corrected, or locked against deletion.
Here’s a closer look at the five that went furthest, and the parts worth reusing. Every entry is browsable in the hackathon project gallery.
The brief was narrower than most hackathons get. Submissions couldn’t just be a working demo and a repo. Devpost required teams to explain, in writing, how their app actually used both Backblaze B2 and Genblaze, and to list every provider and model behind it. Judging ran against four criteria: real-world utility, production readiness, meaningful use of B2, and meaningful use of Genblaze.
That last pair is the constraint that did the work. “Meaningful use” rules out the default architecture, where a team generates an asset, drops the bytes in a bucket, and calls that storage. It forces a decision about what the storage layer is actually for. What follows is written the way a technical and creative director would walk five finished pipelines against exactly that rubric: who each app is actually for, whether it holds up past the demo, and how deep the storage and orchestration choices go.
Backblaze B2 is the ground every one of these apps had to build on: S3-compatible object storage, sized for the sheer volume of generated assets, thumbnails, metadata, and provenance records a media pipeline throws off, free to start with 10GB included.
Genblaze, Backblaze’s open-source orchestration SDK, is what feeds it: a unified Pipeline API spanning providers like OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through platforms such as GMI Cloud and NVIDIA NIM, so a team can swap providers without rewriting its orchestration. Every run produces a canonical provenance manifest that can be embedded directly into the media file itself (an .mp4, a .png, an .mp3) and persisted to B2 or any S3-compatible store.
The hackathon also partnered with GMI Cloud, giving teams easy access to open-source generative models for image, video, audio, chat, reasoning, and multimodal work, which is why it turns up as a provider more than once below.
Two primitives, six weeks, hundreds of teams, and five very different examples of rigor.
https://devpost.com/software/firstframe
github.com/migarci2/firstframe
A review room for AI video ads that doesn’t make you wait for the whole render.
firstframe builds a review room for the marketing and creative teams who commission AI-generated video ads: instead of waiting on a full multi-scene render before anyone can react, it streams the first finished scene as a live HLS playlist the moment it’s ready, appending segments as later scenes land. A reviewer starts giving notes while the ad is still being made, not after.
Every generated scene is scored by an actual vision model before a human ever sees it, so obviously broken output gets caught and retried automatically rather than shipped to a reviewer’s inbox. A failover step swaps in a backup model only on a genuine provider error, never on an ordinary slow response, and once a scene clears review its master file and manifest are locked against deletion for thirty days: a guarantee the code proves by trying to delete a locked file and catching the rejection. Automated QA paired with a tamper-evident record of what was approved is what turns a generation pipeline into something a brand could actually sign off on.
On B2, the bucket’s folder structure doubles as a workflow: a scene moves through incoming, running, provenance, approved, and rejected prefixes as it clears review. Once a scene is approved, its master file and manifest get a real thirty-day write-once hold using B2’s Object Lock in Governance mode, and the code proves that isn’t just decorative by trying to delete a locked object by its version ID and catching the rejection B2 throws back. A reviewer’s application key is scoped to the readFiles capability with a name prefix restricting it to the approved folder alone. Four separate lifecycle rules cover the bucket’s different prefixes: stalled uploads in incoming have their multipart parts cancelled after 24 hours, while rejected, in-progress, and approved objects each age out on their own separate timers. The video segments themselves land in B2 as ffmpeg finishes each one, with the playlist rewritten after every segment, which makes B2 a live broadcast target rather than an archive that fills up after the fact. Reads go out as path-style presigned URLs, working around a known issue where virtual-host-style presigning fails on a private B2 bucket. B2’s own Event Notifications, five signed webhook rules, keep the review room in sync in real time, with a fallback to plain polling if an account’s Event Notifications API isn’t enabled. The app also watches B2’s own transaction cap and backs off to local disk instead of crashing when a call gets rejected for exceeding it.
On Genblaze, generation runs through an AgentLoop scored by a ThresholdEvaluator. The judge is a real vision model, an NVIDIA NIM llama-3.2-90b-vision-instruct instance grading the actual rendered keyframes, not a fixed retry count. Two pipeline branches, audio and video, fan into a single compositor node instead of running as a straight chain, a fallback_models failover is wired in and confirmed to trigger only on a genuine model error rather than a timeout, and every run carries two layers of lineage: a shared run id across scenes and loop iterations, plus a second, custom chain id layered on top of that. The team even embedded the manifest directly inside the delivered MP4, so a separate verification command can re-download and re-hash every asset the file claims exists. Along the way they filed three pull requests and an issue against Genblaze itself.
firstframe puts B2’s feature set to work in front of the reviewer. Object Lock in Governance mode, scoped application keys, lifecycle rules, Event Notifications, and presigned URLs are all load-bearing parts of the review workflow, doing visible work on every scene that moves through it. That’s architecture built to be trusted, not just to work.
https://devpost.com/software/beavous
A campaign generator built to double-check its own storage, re-verifying every asset the moment it’s read back.
beavous is built for the marketers and small commerce teams who need a full paid-social campaign out of a single product photo: not one hero image, but four creative concepts, sixteen cropped aspect ratios for every placement, on-label ad copy, and a portrait video reel, packaged as a verified ZIP pulled straight from B2.
A public API hands off to a private worker behind a task queue, and every campaign is namespaced to an organization so tenants stay isolated from each other. When a generation gets rejected, the app doesn’t start over. It chains a correction onto the original attempt, which is closer to how a real creative review actually works than a one-shot retry.
On B2, keys are organized hierarchically by organization and campaign rather than by content hash, because the product is multi-tenant by design. Every upload and download goes through a presigned URL, and the database never stores a raw link, only an object key and a hash. Every time an asset is read back, beavous re-downloads it and re-hashes the bytes independently, rather than trusting a manifest check alone. B2 is treated as the single, sole system of record for every generated asset: a clean, one-source-of-truth design with nothing else to keep in sync.
On Genblaze, three custom providers handle Gemini image generation, Gemini video, and Veo image-to-video, each with its own tiered pricing registered on the model. The more interesting move is a correction chain: when a generation gets rejected, its manifest becomes the parent of the next attempt, an explicit correction lineage most one-shot generation pipelines skip entirely. Prompts are marked private so the text never lands in the public manifest, only a hashed reference to it does, and before any manifest is trusted as a correction parent it gets independently re-verified, not assumed correct just because it was the app’s own write.
beavous’s answer to “do you trust your own storage” is simple: no, never. Check it again, every time. That’s a slower design than trusting your own write, and a more honest one.
https://devpost.com/software/takegraph
A build system for generative media that can prove its own reuse, recovery, and release integrity, live, against B2.
takegraph is built for teams running a production, not a single generation: the kind of project where a script tweak halfway through shouldn’t mean re-rendering everything from scratch. It treats the whole thing like a software build: a content-addressed dependency graph that, when a spec changes, recomputes fingerprints, rebuilds only what’s actually invalidated, and reuses everything else.
A team can also re-download and re-hash the actual bytes behind any reuse, recovery, or release straight from B2, live, checking integrity themselves instead of trusting a log. That kind of self-auditing separates a pipeline meant to run unattended for months from one built to survive a single demo.
On B2, content-addressed keys use a two-level hash split so directory listings stay fast at scale, B2’s own Event Notifications (HMAC-SHA256-signed webhooks) feed a background process, and a separate reconciler periodically re-checks everything by hand in case a webhook is ever missed, coordinated across workers with a database lock so only one reconciler runs at a time. Unvalidated uploads land in a quarantine prefix backed by a real lifecycle rule that expires it automatically, and a bad key gets rejected outright rather than silently rewritten. Two least-privilege application keys, one for day-to-day work and one for releases, are each scoped to a single bucket, and CORS rules on the work bucket exist specifically to support presigned browser uploads. Verification (re-download, re-hash, prove it) is a feature of the product, not an internal tool.
On Genblaze, takegraph builds a real pipeline around the idea: a dedicated run builder, a content-addressable storage sink, manifests, and observability events tied to every step. The team kept its media-generation side lean, calling straight through the GMI Cloud connector for image and video (one of the hackathon’s partner platforms), and pointed all of its custom engineering at the layer that makes the whole pitch work: the storage and consistency system underneath.
takegraph turns storage verification into the product itself: reuse, recovery, and release integrity are things a user can ask the system to prove, live, rather than take on faith. That’s B2 treated as a system of record in the fullest sense: self-healing, event-driven, and built to survive a missed webhook without anyone noticing.
https://devpost.com/software/ninth-mkcgtv
A comic studio with a provider for every model it needed, and a manifest for every frame it drew.
Ninth is built for indie comic authors and motion-comic creators working on a small budget, who revise a scene a dozen times before it’s right and can’t afford to pay for a fresh generation on every pass. Describe a story, and it writes, draws, casts, and stages it panel by panel on an editable timeline, then bakes the result to an MP4.
An edit doesn’t force a re-generation: assets are pulled from a semantic library whenever something close enough already exists, and everything the AI produces (timing, layer position, camera, bubble placement, even the artwork itself) stays editable in place afterward. That reuse-first design is backed by 126 regression tests and a render path that shares its engine with the live editor, so what a creator previews is exactly what gets exported.
Its B2 layer favors verified durability: flat content-addressed keys and a manifest per run, plus real, working endpoints for audit, restore, and backfill that report exactly what’s on B2 versus what’s only on local disk, and rebuild the difference with a SHA-256 check on every recovered file.
On Genblaze, Ninth wrote seven or eight custom providers, covering nearly every model it reached for: Azure’s image model, Gemini’s aspect ratios, Veo keyframes, Gemini’s video interpolation model, ElevenLabs music, and two separate structured-text providers. Each one exists for the same reason: to keep that artifact inside a pipeline and give it a manifest, so a generated frame always carries a record of the run and the prompt that made it.
Ninth’s mention is for discipline: the project that took “every generated frame should be reproducible and recoverable” most literally, and built the tooling to prove it on demand.
https://devpost.com/software/spatialize
A spatial twin that gives a person’s spoken correction the same provenance as a model’s output.
Spatialize is built for venue and accessibility teams who need to rehearse a step-free route through a space before anyone sets foot in it: it turns a flat floor plan into a voice-navigable spatial twin, extracting validated 3D geometry from the plan image, then answering spoken questions with route guidance grounded in that geometry.
Because the underlying use case is safety-adjacent, nothing the model proposes is trusted outright. Every extracted floor plan, and every voice-driven edit to it, has to pass the same deterministic geometry validator before it’s accepted, so a plausible-looking but wrong route never quietly makes it into a rehearsal. When that validator rejects an attempt, it hands back the exact error, and the next attempt corrects specifically that, not a blind retry.
On B2, Spatialize favors resilience: every read goes through a short-lived, presigned link, and if B2 isn’t configured at all, the app quietly falls back to a local, path-safe store instead of failing to boot. It runs two storage paths side by side (its own hierarchical object store for run and scene state, and a separate Genblaze storage sink dedicated to generated-media provenance), keeping application state and generation history cleanly apart.
Under the hood, an agentic loop drives the floor-plan extraction, evaluated at each attempt by that same deterministic validator rather than an LLM’s opinion. Three custom text-to-speech providers form a genuine fallback ladder: a cloud model first, a lightweight third-party API next, and a self-hosted, zero-credential model as the last resort, so a narration request degrades gracefully rather than failing outright. The standout idea: a voice-driven edit to the scene creates a new version tagged as a human change, with the actual transcript kept as evidence, so every point in the final scene traces back to either a model’s manifest or a person’s own words.
Spatialize’s real achievement is conceptual: it gives a spoken correction the same seriousness as a model’s output, tracing every point in the final scene back to either a manifest or a transcript. That’s provenance thinking applied somewhere most generative pipelines never point it.
Every winning project found its own discipline. What they share is how many different, equally valid kinds of rigor a small team can bring to the same two primitives in six weeks. firstframe made B2’s write-once guarantee visible to a reviewer in real time. beavous made re-verification a habit instead of an afterthought. takegraph made its storage layer heal itself. Ninth made every one of its seven custom providers answerable to the same manifest. Spatialize made a human correction as provable as a model’s.
None of that shows up until a team stops treating storage and orchestration as plumbing and starts treating them as part of the design. firstframe’s win sits at the intersection of both: the same rigor that scores a generated frame with a vision model also locks the finished one against deletion.
Strip the five projects back and the same handful of moves keep appearing, none of which need a hackathon, a large team, or a novel model:
All of it is available today. B2 starts free with 10GB, and Object Lock, lifecycle rules, Event Notifications, scoped application keys, and presigned URLs are in the API from day one. Genblaze gives you one Pipeline API across OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through GMI Cloud and NVIDIA NIM, and a canonical provenance manifest out of every run that embeds straight into the .mp4, .png, or .mp3 you ship.
A good first project is smaller than any of these five. Take a pipeline you already have, write a manifest for every run, persist it to B2, and add one endpoint that re-downloads and re-hashes an asset to prove the manifest is honest. That’s a weekend of work, and everything above is a variation on it. Genblaze is open source, and three of the pull requests behind firstframe are already in it.
For more ideas, the full project gallery has every entry from the hackathon, and there’s a lot in there beyond the five covered here.
The post Results from the Backblaze Generative AI Media Hackathon appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Post Syndicated from daroc original https://lwn.net/Articles/1087823/
Ihor Solodrai and Shung-Hsi Yu wrapped up the BPF track at the 2026
Linux
Storage, Filesystem, Memory-Management, and BPF Summit with a pair of
sessions related to testing.
Solodrai spoke about what has changed for BPF’s continuous-integration (CI)
testing. Yu spoke about what may be
needed to test BPF updates in stable kernels more thoroughly. The
BPF subsystem’s CI tests are in a good place, they said; even so, Solodrai and Yu have a
handful of possible avenues toward enabling better test coverage in the future.
Post Syndicated from Ambarish Rao original https://aws.amazon.com/blogs/big-data/how-autodesk-migrated-2-3-billion-documents-to-amazon-opensearch-service-using-migration-assistant-and-intelligent-routing/
OpenSearch is an open source software suite for search, analytics, security monitoring, and observability applications, licensed under the Apache License V2.0. Amazon OpenSearch Service is a managed service that lets you deploy, scale, and operate OpenSearch and the Elasticsearch engine in the AWS Cloud. Customers run search workloads on OpenSearch Service at a scale of billions of documents. When a single index holds millions to billions of documents, you need to plan the topology of the OpenSearch Service domain that holds the index. This post walks through how Autodesk re-architected a single-index Elasticsearch 7.1.1 domain on Amazon OpenSearch Service into four multi-index OpenSearch Service domains, using Migration Assistant for Amazon OpenSearch Service and a routing layer that directs each query to the shards that hold the data for that query.
Autodesk is a technology company that serves customers across three industry verticals: Architecture, Engineering, and Construction (AEC), Product Design and Manufacturing, and Media and Entertainment. Autodesk’s mission is to empower everyone, everywhere to design and make anything, helping customers work across the boundaries of project, discipline, and industry.
Autodesk Forma (formerly Autodesk Construction Cloud, or ACC) is a cloud-based construction management and collaboration system. Customers across the globe use Autodesk Forma for workflows that include document management, bid management, quantification, coordination, design collaboration, project management and field collaboration. Autodesk Forma uses Amazon OpenSearch Service to provide a search experience for millions of users. As customers add data, the data that Forma stores in OpenSearch Service grows. In an OpenSearch Service domain, an index is the unit of data storage and organization. When an index reaches 100 TB, the index becomes a performance bottleneck and is hard to scale. As Autodesk Forma grew, Forma data management (formerly Autodesk Docs) hit performance and scaling limits. This component supports access and search across the project catalog.
Forma data management ran on a single Elasticsearch 7.1.1 domain on Amazon OpenSearch Service with one index. The domain held about 100 TB of data on over 100 data nodes with over 400 primary shards and a replication factor of 1. The average shard held 200 GB. Because of the scale and the production state of the domain, tuning techniques such as adding shards, adding indices, or rebalancing data were not viable.
The single-index, single-domain design exposed three challenges to future data growth:
Vertical or horizontal scaling can address query performance in the short term, but neither addresses the underlying single-index, single-domain scalability limit. A horizontal scaling approach that uses routing keys gives you control over which shards each query touches, without requiring larger hardware. The Autodesk team applied this approach to re-architect the search service without impacting production traffic.
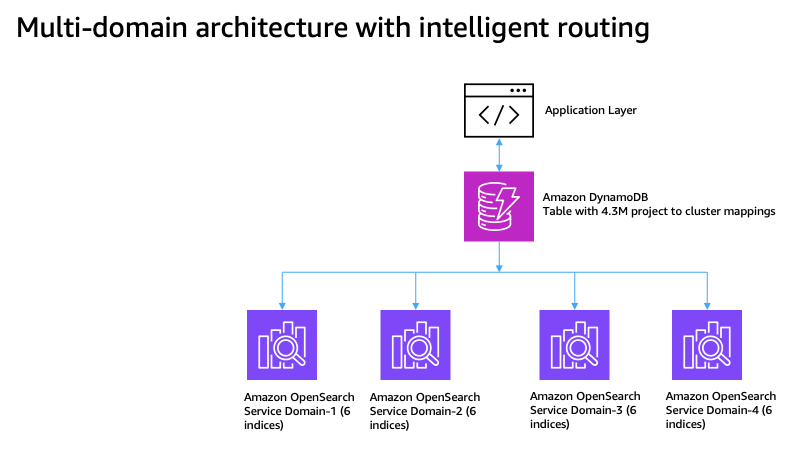
Figure 1: Multi-domain architecture with intelligent routing
The architecture has the following properties:
m7i.4xlarge.search nodes.The setup uses four horizontally scaled OpenSearch Service domains, with a routing layer that directs each query to the domain that holds the project’s data.
The architecture uses a Amazon DynamoDB table that stores 4.3 million routing records, one record per project. A project is the primary workspace in Forma data management, where teams, data, documents, models, workflows, permissions, issues, and collaboration activities live together. Forma application looks up the Amazon DynamoDB table for the project-to-domain mapping and then issues the search query to the correct domain.
Redistributing millions of records across four domains was hard. To find an even project-to-index allocation, the team used a bin-packing algorithm. A bin-packing algorithm packs items of varying sizes into a fixed number of bins to minimize waste and produce an even distribution. The team worked with 4.3 million projects of varying document counts, from a few documents per project up to millions, across 24 indices that each target around 400 million documents. The team implemented a stratified bin-packing algorithm that uses historical usage metrics for the workload. This algorithm avoids over- or under-allocation of resources during migration planning. To avoid over-allocation, the team used the 95th percentile (P95) usage metric. After applying the algorithm, each OpenSearch Service domain landed at about 49 percent utilization, which leaves a 2x growth buffer. The application then uses routing-key-based queries to search only the relevant shards, instead of every shard in the index.
The architecture has the following benefits:
The following sections describe the four steps the Autodesk team followed to complete the migration.
The team grouped projects into four size categories by current document count, then collected data over six months to compute a per-category growth factor and extrapolate one year out:
| Category | Document range | Project count | % of total | P95 growth factor | Rationale |
| TINY | 0 – 1,000 | 4,085,310 | 95.0% | 3.82x | Tiny projects grow fastest |
| SMALL | 1,000 – 10,000 | 184,347 | 4.3% | 2.11x | Moderate growth expected |
| MEDIUM | 10,000 – 100,000 | 28,385 | 0.66% | 1.72x | Slower relative growth |
| LARGE | 100,000+ | 2,266 | 0.05% | 1.38x | Already mature, minimal growth |
| Total | — | 4,300,308 | 100% | — | — |
The table shows that 95 percent of projects are TINY, but LARGE projects account for the bulk of document volume. The stratification by category lets the algorithm handle each category appropriately.
The Autodesk team analyzed document count per project over six months to estimate growth. Using the P95 growth factor per category gives a conservative capacity plan that covers 95 percent of projects and avoids over-provisioning.
If you process all LARGE projects first, you create imbalance across the indices. To avoid this imbalance, the bin-packing algorithm interleaves the categories in a round-robin pattern. The team used the following sequence to distribute documents evenly across the Amazon OpenSearch Service domains:
After interleaving, the team computed the projected size of each project and assigned the project to an index. The following steps describe the approach:
current size × growth factor.The preceding three steps produced the following results:
The team stored the project-to-index allocation mapping in Amazon DynamoDB for real-time query routing. Routing controls how the application uses domain resources and how each domain performs. With routing, the application searches the shards that match the routing key (projectId) for that project. Without routing, the same query searches every shard in the index, which wastes domain resources and produces slower queries. The team also tuned the shard size, which matters most for large projects. One of the largest projects held 7 million documents at about 40 KB per document, for a total of about 280 GB. To split the data for that project into 20–25 GB shards, the team set routing_partition_size to 12.
The Autodesk team used the snapshot and re-index path in Migration Assistant for Amazon OpenSearch Service to migrate 2.3 billion documents. Migration Assistant for Amazon OpenSearch Service adapts to the migration profile and provides AWS Identity and Access Management (IAM) permission boundaries, Amazon Virtual Private Cloud (Amazon VPC) support, and the security policies the migration needs. Migration Assistant for Amazon OpenSearch Service integrated with the over 400 tasks that run the application on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate.
Before the production cutover, the team ran several proof-of-concept (PoC) iterations and tuned the migration configuration to raise throughput from 18 GB/hr to 228 GB/hr. The first PoC iteration hit 18 GB/hr on m7g.large.search nodes. Each subsequent iteration added horizontal scale, larger instances (m7g.2xlarge.search and m7g.4xlarge.search), parallel writes across domains, and zero replicas during migration. The fourth and final PoC iteration hit 228 GB/hr. Multiple PoC iterations helped the team select the optimal instance size and instance class to migrate 2.3 billion documents in 6 hours with zero downtime and no customer incidents.
After the team migrated 2.3 billion documents with routing enabled, the shards landed as follows:
| Metric | Result | Target | Status |
| Total primary shards | 4,325 | — | ✓ |
| Total data size | 52.11 TB | ~52 TB | ✓ On target |
| Average shard size | 12.34 GB | 10–15 GB | ✓ Optimal |
| Median shard size | 11.9 GB | 10–15 GB | ✓ Optimal |
| Shards in optimal range (10–15 GB) | 75.5% | 70% | ✓ Above target |
| Hot shards (> 30 GB) | 12 (0.28%) | < 1% | ✓ Within limit |
| Undersized shards (< 10 GB) | 528 (12.2%) | < 15% | ✓ Within limit |
| Cross-domain balance | 2.3% variance | < 5% | ✓ Within target |
| Node balance (StdDev) | 0.78–1.12 shards | < 2 | ✓ Within target |
The following table compares the pre- and post-migration architectures:
| Aspect | Old (single domain) | New (four domains with intelligent routing) |
| Shard size | 200 GB average | 12.34 GB average (94% reduction) |
| Query broadcast | All 400+ shards | ~12 shards (97% reduction) |
| Shards in optimal range | 0% | 75.5% |
| Cross-domain balance | N/A (single domain) | 2.3% variance |
| Storage | 83.3 TB | 52 TB |
| Total P99 query latency | 17 seconds | 5 seconds |
The team migrated 2.3 billion documents in about 6 hours. Storage dropped by about 37 percent, from 83.3 TB to 52 TB, because the migration dropped deleted documents. The migration produced 4,325 shards at an average of 12.34 GB per shard, distributed across the four domains. 75.5 percent of shards landed in the 10–15 GB range, compared to 210 GB before the migration, which confirms that the new architecture solves the large-shard problem. The shard size is as per general guidance where search latency is a key performance objective. Cross-domain variance of 2.3 percent (12.85 TB to 13.15 TB per domain) confirms even data distribution.
After the migration, queries that include the projectId routing key scan only the relevant shards (typically 12 of 180 per index), which reduces search load across shards by 93 percent. Routing also balances CPU and memory use across each domain. The routing_partition_size of 12 per index produced the right shard count per index. Overall P99 latency improved by 72 percent, from 17 seconds to 5 seconds. Within that figure, search-query P99 improved by 92 percent, from 2,500 ms to 200 ms.
The PoC iterations surfaced several lessons. Larger instance types help query performance in the short term, but query routing combined with horizontal scaling produces higher sustained throughput. During bulk loads, disable replicas and increase the refresh interval to reduce write overhead. Plan for enough IP addresses and subnet capacity when you scale the application out, so that you do not hit a service limit mid-migration. Validate the VPC routing configuration between the application and the OpenSearch Service domains. Confirm OpenSearch Service data-node capacity with AWS Support before a horizontal scale-out. The Amazon DynamoDB-based routing layer adds about 20 ms of routing latency per query, but the routing layer cuts overall search latency and unlocks horizontal scale.
In this post, you saw how the Autodesk team migrated 2.3 billion documents from a single-index domain to four multi-index Amazon OpenSearch Service domains in about 6 hours.
Transitioning to a multi-domain architecture or updating to the latest OpenSearch version has historically been complex. It can also be difficult to predict the outcome of a migration before production traffic moves. The Migration Assistant for Amazon OpenSearch Service solution addresses these challenges by making migration workflow-driven, repeatable, and more straightforward to validate before cutover.
Migration Assistant for Amazon OpenSearch Service coupled with Amazon DynamoDB-based intelligent routing helped achieve balanced shards and improved search query performance. Multiple PoC iterations helped find routing bugs, service-quota limitations, and infrastructure-provisioning gaps before the production cutover.
If you plan to migrate a large dataset between OpenSearch Service domains, you can use Migration Assistant for Amazon OpenSearch Service. For more information, see the Migration Assistant for Amazon OpenSearch Service documentation.