Tag Archives: Amazon VPC

How Autodesk migrated 2.3 billion documents to Amazon OpenSearch Service using Migration Assistant and intelligent routing

Post Syndicated from Ambarish Rao original https://aws.amazon.com/blogs/big-data/how-autodesk-migrated-2-3-billion-documents-to-amazon-opensearch-service-using-migration-assistant-and-intelligent-routing/

OpenSearch is an open source software suite for search, analytics, security monitoring, and observability applications, licensed under the Apache License V2.0. Amazon OpenSearch Service is a managed service that lets you deploy, scale, and operate OpenSearch and the Elasticsearch engine in the AWS Cloud. Customers run search workloads on OpenSearch Service at a scale of billions of documents. When a single index holds millions to billions of documents, you need to plan the topology of the OpenSearch Service domain that holds the index. This post walks through how Autodesk re-architected a single-index Elasticsearch 7.1.1 domain on Amazon OpenSearch Service into four multi-index OpenSearch Service domains, using Migration Assistant for Amazon OpenSearch Service and a routing layer that directs each query to the shards that hold the data for that query.

Autodesk is a technology company that serves customers across three industry verticals: Architecture, Engineering, and Construction (AEC), Product Design and Manufacturing, and Media and Entertainment. Autodesk’s mission is to empower everyone, everywhere to design and make anything, helping customers work across the boundaries of project, discipline, and industry.

Autodesk Forma (formerly Autodesk Construction Cloud, or ACC) is a cloud-based construction management and collaboration system. Customers across the globe use Autodesk Forma for workflows that include document management, bid management, quantification, coordination, design collaboration, project management and field collaboration. Autodesk Forma uses Amazon OpenSearch Service to provide a search experience for millions of users. As customers add data, the data that Forma stores in OpenSearch Service grows. In an OpenSearch Service domain, an index is the unit of data storage and organization. When an index reaches 100 TB, the index becomes a performance bottleneck and is hard to scale. As Autodesk Forma grew, Forma data management (formerly Autodesk Docs) hit performance and scaling limits. This component supports access and search across the project catalog.

Where Autodesk started

Forma data management ran on a single Elasticsearch 7.1.1 domain on Amazon OpenSearch Service with one index. The domain held about 100 TB of data on over 100 data nodes with over 400 primary shards and a replication factor of 1. The average shard held 200 GB. Because of the scale and the production state of the domain, tuning techniques such as adding shards, adding indices, or rebalancing data were not viable.

The single-index, single-domain design exposed three challenges to future data growth:

  1. Query performance. Query latency degraded over time as data grew.
  2. Vertical scaling. The team had reached the limit of the largest Amazon Elastic Compute Cloud (Amazon EC2) instance size available for the existing instance class.
  3. Horizontal scaling. Without a routing mechanism, adding nodes produced hot nodes inside the cluster managed by the OpenSearch Service domain.

Multi-domain architecture with intelligent routing

Vertical or horizontal scaling can address query performance in the short term, but neither addresses the underlying single-index, single-domain scalability limit. A horizontal scaling approach that uses routing keys gives you control over which shards each query touches, without requiring larger hardware. The Autodesk team applied this approach to re-architect the search service without impacting production traffic.
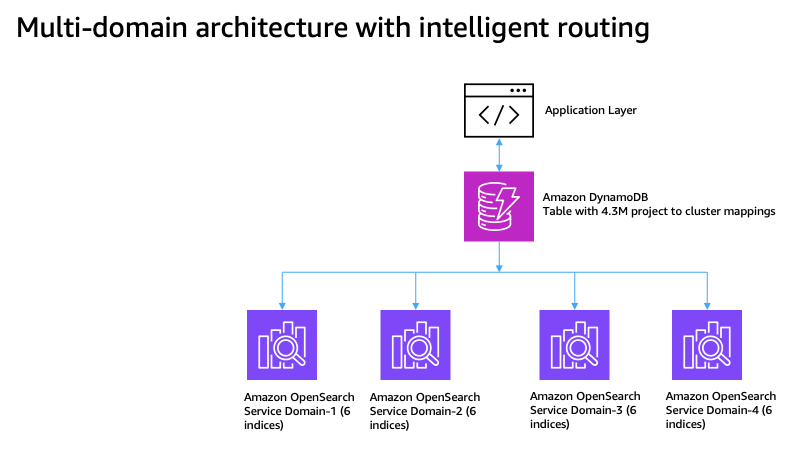
Four Amazon OpenSearch Service domains with an Amazon DynamoDB routing layer directing each query to the correct domain

Figure 1: Multi-domain architecture with intelligent routing

The architecture has the following properties:

  • Four Amazon OpenSearch Service domains on OpenSearch 2.19, each running 24 m7i.4xlarge.search nodes.
  • 24 indices total (6 per domain).
  • About 95 million documents per index.
  • 52 TB of primary storage. This is 37 percent smaller than the primary storage size of the original single-index domain, mainly because the migration skipped deleted documents.

The setup uses four horizontally scaled OpenSearch Service domains, with a routing layer that directs each query to the domain that holds the project’s data.

The architecture uses a Amazon DynamoDB table that stores 4.3 million routing records, one record per project. A project is the primary workspace in Forma data management, where teams, data, documents, models, workflows, permissions, issues, and collaboration activities live together. Forma application looks up the Amazon DynamoDB table for the project-to-domain mapping and then issues the search query to the correct domain.

Redistributing millions of records across four domains was hard. To find an even project-to-index allocation, the team used a bin-packing algorithm. A bin-packing algorithm packs items of varying sizes into a fixed number of bins to minimize waste and produce an even distribution. The team worked with 4.3 million projects of varying document counts, from a few documents per project up to millions, across 24 indices that each target around 400 million documents. The team implemented a stratified bin-packing algorithm that uses historical usage metrics for the workload. This algorithm avoids over- or under-allocation of resources during migration planning. To avoid over-allocation, the team used the 95th percentile (P95) usage metric. After applying the algorithm, each OpenSearch Service domain landed at about 49 percent utilization, which leaves a 2x growth buffer. The application then uses routing-key-based queries to search only the relevant shards, instead of every shard in the index.

The architecture has the following benefits:

  • Horizontal scalability. The team can add more domains and indices as needed.
  • Efficient routing. Queries hit specific shards, not every shard in the domain.
  • Reduced blast radius. If one domain becomes unavailable, only about 25% of traffic is affected, instead of full downtime under the single-domain design.
  • Independent scaling. The team can scale each domain based on its load pattern.
  • More search threads. The aggregate search-thread pool is larger across four domains than on one domain.

Migration steps

The following sections describe the four steps the Autodesk team followed to complete the migration.

Step 1: Categorize projects by size

The team grouped projects into four size categories by current document count, then collected data over six months to compute a per-category growth factor and extrapolate one year out:

Category Document range Project count % of total P95 growth factor Rationale
TINY 0 – 1,000 4,085,310 95.0% 3.82x Tiny projects grow fastest
SMALL 1,000 – 10,000 184,347 4.3% 2.11x Moderate growth expected
MEDIUM 10,000 – 100,000 28,385 0.66% 1.72x Slower relative growth
LARGE 100,000+ 2,266 0.05% 1.38x Already mature, minimal growth
Total 4,300,308 100%

The table shows that 95 percent of projects are TINY, but LARGE projects account for the bulk of document volume. The stratification by category lets the algorithm handle each category appropriately.

The Autodesk team analyzed document count per project over six months to estimate growth. Using the P95 growth factor per category gives a conservative capacity plan that covers 95 percent of projects and avoids over-provisioning.

Step 2: Interleaved distribution

If you process all LARGE projects first, you create imbalance across the indices. To avoid this imbalance, the bin-packing algorithm interleaves the categories in a round-robin pattern. The team used the following sequence to distribute documents evenly across the Amazon OpenSearch Service domains:

  1. Sort the projects within each category, largest first.
  2. Create a queue for each category. The queue is a first-in, first-out data structure that holds the sorted projects for one category.
  3. Distribute projects in a round-robin pattern: pick one from LARGE, then MEDIUM, then SMALL, then TINY, and repeat.

Step 3: Load-balanced best fit

After interleaving, the team computed the projected size of each project and assigned the project to an index. The following steps describe the approach:

  1. Compute the estimated future size as current size × growth factor.
  2. Use a priority queue to find the index with the most available capacity. In a priority queue, each element has a priority. Here, the priority of each index is the amount of available capacity the index has. Unlike a regular queue, a priority queue returns the highest-priority element first, not the first one inserted.
  3. Assign the project to the index that has the most available capacity.
  4. Update the index’s estimated load and re-insert the index into the priority queue with the new capacity. The re-insert step keeps the queue accurate for the next project assignment.

The preceding three steps produced the following results:

  • The algorithm distributed 4.3 million projects with 99.999 percent routing accuracy.
  • Project distribution across indices held to a 0.15 percent variance.
  • Each domain landed at 49.1 percent capacity utilization after applying growth factors, leaving 50.9 percent headroom for future growth.
  • The algorithm computed the 4.3 million project allocations in about 10 minutes.

The team stored the project-to-index allocation mapping in Amazon DynamoDB for real-time query routing. Routing controls how the application uses domain resources and how each domain performs. With routing, the application searches the shards that match the routing key (projectId) for that project. Without routing, the same query searches every shard in the index, which wastes domain resources and produces slower queries. The team also tuned the shard size, which matters most for large projects. One of the largest projects held 7 million documents at about 40 KB per document, for a total of about 280 GB. To split the data for that project into 20–25 GB shards, the team set routing_partition_size to 12.

Step 4: Migration with Migration Assistant for Amazon OpenSearch Service

The Autodesk team used the snapshot and re-index path in Migration Assistant for Amazon OpenSearch Service to migrate 2.3 billion documents. Migration Assistant for Amazon OpenSearch Service adapts to the migration profile and provides AWS Identity and Access Management (IAM) permission boundaries, Amazon Virtual Private Cloud (Amazon VPC) support, and the security policies the migration needs. Migration Assistant for Amazon OpenSearch Service integrated with the over 400 tasks that run the application on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate.

Before the production cutover, the team ran several proof-of-concept (PoC) iterations and tuned the migration configuration to raise throughput from 18 GB/hr to 228 GB/hr. The first PoC iteration hit 18 GB/hr on m7g.large.search nodes. Each subsequent iteration added horizontal scale, larger instances (m7g.2xlarge.search and m7g.4xlarge.search), parallel writes across domains, and zero replicas during migration. The fourth and final PoC iteration hit 228 GB/hr. Multiple PoC iterations helped the team select the optimal instance size and instance class to migrate 2.3 billion documents in 6 hours with zero downtime and no customer incidents.

Post-migration analysis

After the team migrated 2.3 billion documents with routing enabled, the shards landed as follows:

Metric Result Target Status
Total primary shards 4,325
Total data size 52.11 TB ~52 TB ✓ On target
Average shard size 12.34 GB 10–15 GB ✓ Optimal
Median shard size 11.9 GB 10–15 GB ✓ Optimal
Shards in optimal range (10–15 GB) 75.5% 70% ✓ Above target
Hot shards (> 30 GB) 12 (0.28%) < 1% ✓ Within limit
Undersized shards (< 10 GB) 528 (12.2%) < 15% ✓ Within limit
Cross-domain balance 2.3% variance < 5% ✓ Within target
Node balance (StdDev) 0.78–1.12 shards < 2 ✓ Within target

The following table compares the pre- and post-migration architectures:

Aspect Old (single domain) New (four domains with intelligent routing)
Shard size 200 GB average 12.34 GB average (94% reduction)
Query broadcast All 400+ shards ~12 shards (97% reduction)
Shards in optimal range 0% 75.5%
Cross-domain balance N/A (single domain) 2.3% variance
Storage 83.3 TB 52 TB
Total P99 query latency 17 seconds 5 seconds

The team migrated 2.3 billion documents in about 6 hours. Storage dropped by about 37 percent, from 83.3 TB to 52 TB, because the migration dropped deleted documents. The migration produced 4,325 shards at an average of 12.34 GB per shard, distributed across the four domains. 75.5 percent of shards landed in the 10–15 GB range, compared to 210 GB before the migration, which confirms that the new architecture solves the large-shard problem. The shard size is as per general guidance where search latency is a key performance objective. Cross-domain variance of 2.3 percent (12.85 TB to 13.15 TB per domain) confirms even data distribution.

After the migration, queries that include the projectId routing key scan only the relevant shards (typically 12 of 180 per index), which reduces search load across shards by 93 percent. Routing also balances CPU and memory use across each domain. The routing_partition_size of 12 per index produced the right shard count per index. Overall P99 latency improved by 72 percent, from 17 seconds to 5 seconds. Within that figure, search-query P99 improved by 92 percent, from 2,500 ms to 200 ms.

Lessons learned

The PoC iterations surfaced several lessons. Larger instance types help query performance in the short term, but query routing combined with horizontal scaling produces higher sustained throughput. During bulk loads, disable replicas and increase the refresh interval to reduce write overhead. Plan for enough IP addresses and subnet capacity when you scale the application out, so that you do not hit a service limit mid-migration. Validate the VPC routing configuration between the application and the OpenSearch Service domains. Confirm OpenSearch Service data-node capacity with AWS Support before a horizontal scale-out. The Amazon DynamoDB-based routing layer adds about 20 ms of routing latency per query, but the routing layer cuts overall search latency and unlocks horizontal scale.

Conclusion

In this post, you saw how the Autodesk team migrated 2.3 billion documents from a single-index domain to four multi-index Amazon OpenSearch Service domains in about 6 hours.

Transitioning to a multi-domain architecture or updating to the latest OpenSearch version has historically been complex. It can also be difficult to predict the outcome of a migration before production traffic moves. The Migration Assistant for Amazon OpenSearch Service solution addresses these challenges by making migration workflow-driven, repeatable, and more straightforward to validate before cutover.

Migration Assistant for Amazon OpenSearch Service coupled with Amazon DynamoDB-based intelligent routing helped achieve balanced shards and improved search query performance. Multiple PoC iterations helped find routing bugs, service-quota limitations, and infrastructure-provisioning gaps before the production cutover.

If you plan to migrate a large dataset between OpenSearch Service domains, you can use Migration Assistant for Amazon OpenSearch Service. For more information, see the Migration Assistant for Amazon OpenSearch Service documentation.
About the authors

Ambarish Rao

Ambarish Rao

Ambarish is a Principal Engineer at Autodesk Search Team. He is based out of Pune. With 11 years of experience across financial data, logistics and now design and manufacturing, he has worked on mid to large scale distributed systems. When not working on Search, he’s either swimming, playing badminton, volunteering to teach kids, or hunting for Pune’s best biryani.

Chengsi Xie

Chengsi Xie

Chengsi is a Software Development Engineer on Autodesk Search Team. He is focused on building scalable distributed search platforms. He enjoys digging into the root causes behind problems and understanding how systems behave. Outside of work, he likes to stay active through running, playing badminton, hiking, and other outdoor activities that help him stay energized and grounded.

Manoj Kale

Manoj Kale

Manoj is a Senior Solutions Architect at Amazon Web Services. He helps customers design and build scalable, resilient solutions on AWS. He specializes in cloud architecture, AI/ML, and DevOps, and enjoys working with customers to solve complex technical challenges. Outside of work, he likes to spend time with family, travel and log the travel through travel logs and photos.

Anirudh Gupta

Anirudh Gupta

Anirudh is a Technical Account Manager at Amazon Web Services. He works closely with enterprise customers to help them architect, optimize, and operate their workloads on AWS. He is passionate about helping customers modernize their infrastructure and scale distributed systems on AWS.

Priyanshi Omer

Priyanshi Omer

Priyanshi is a Solutions Architect at Amazon Web Services. She helps customers design and build scalable, resilient solutions on AWS. She specializes in cloud architecture, AI/ML, and DevOps, and enjoys working with customers to solve complex technical challenges.

Accelerating AWS Network Firewall troubleshooting with AWS DevOps Agent

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/security/accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent/

When an administrator introduces a rule change in AWS Network Firewall and network connectivity is disrupted, pinpointing the cause requires inspecting multiple points in the traffic path. The firewall gives you stateless and stateful rule engines, domain rules, and routing to the firewall endpoint inside your Amazon Virtual Private Cloud (Amazon VPC). A network drop looks the same from the workload no matter where it started. Isolating the cause means correlating the alert and flow logs with the firewall configuration, route tables, and recent API calls in AWS CloudTrail that might have changed them. That manual correlation is exactly where AWS DevOps Agent helps, accelerating root cause analysis so you can restore connectivity in minutes instead of hours.

AWS DevOps Agent does that correlation for you. As your always-available operations teammate, it resolves and proactively prevents operational issues across AWS, multicloud, and on-premises environments. When an Amazon CloudWatch alarm triggers, it reaches the agent through a webhook. The agent then reads the firewall configuration and logs through AWS APIs, ties the drop to recent API activity, and returns a root cause with a mitigation plan you review before you apply it.

This post connects CloudWatch monitoring to DevOps Agent. It walks through three Network Firewall failures from end to end. The first is a domain deny list blocking a legitimate endpoint. The second is a stateless rule priority misconfiguration. The third is an asymmetric cross Availability Zone (AZ) routing drop. Each maps to a different layer, so each leads down a different investigation path. An AWS Cloud Development Kit (AWS CDK) app deploys the whole environment in your own account so you can reproduce each failure and follow along.

The sample workload

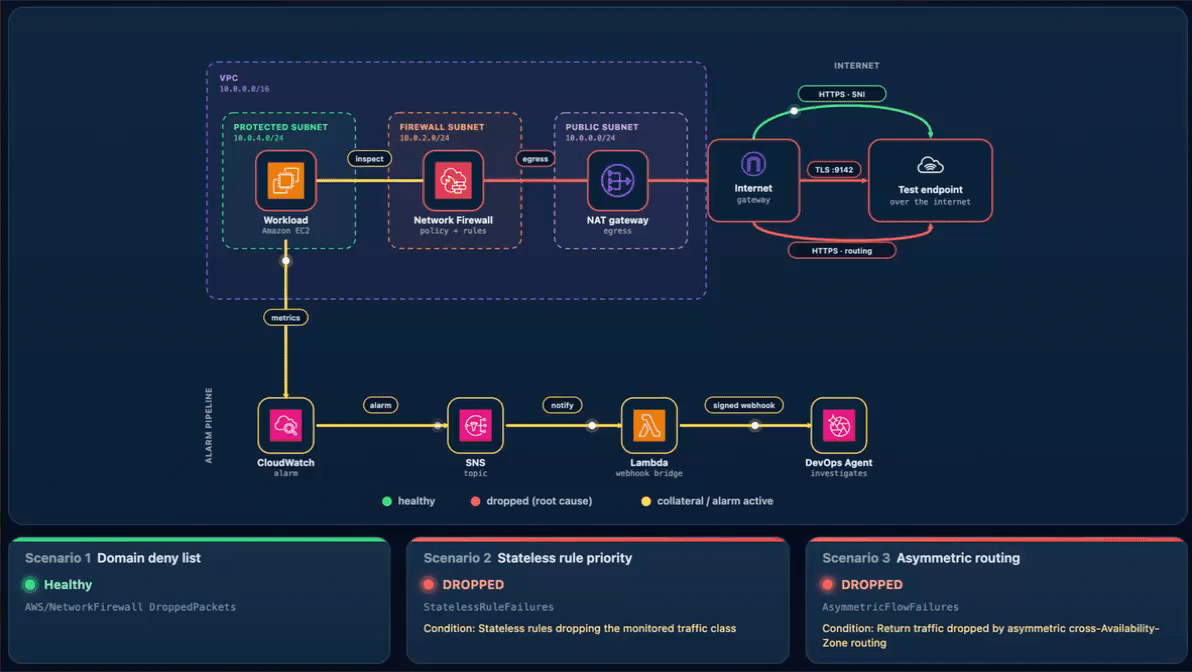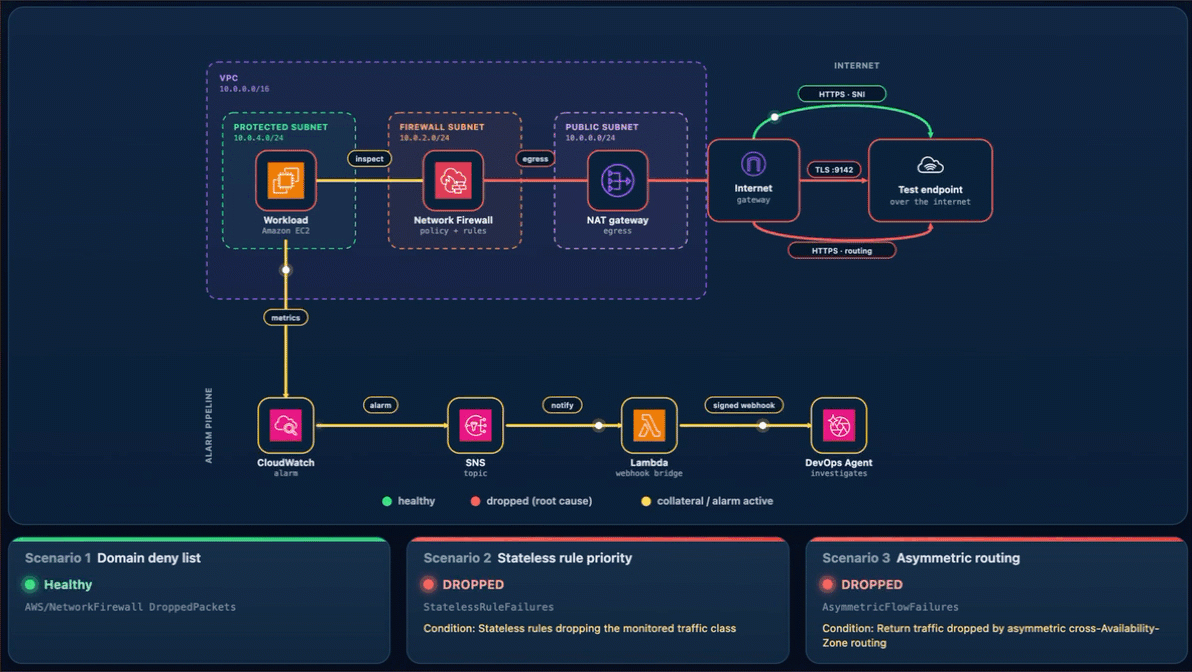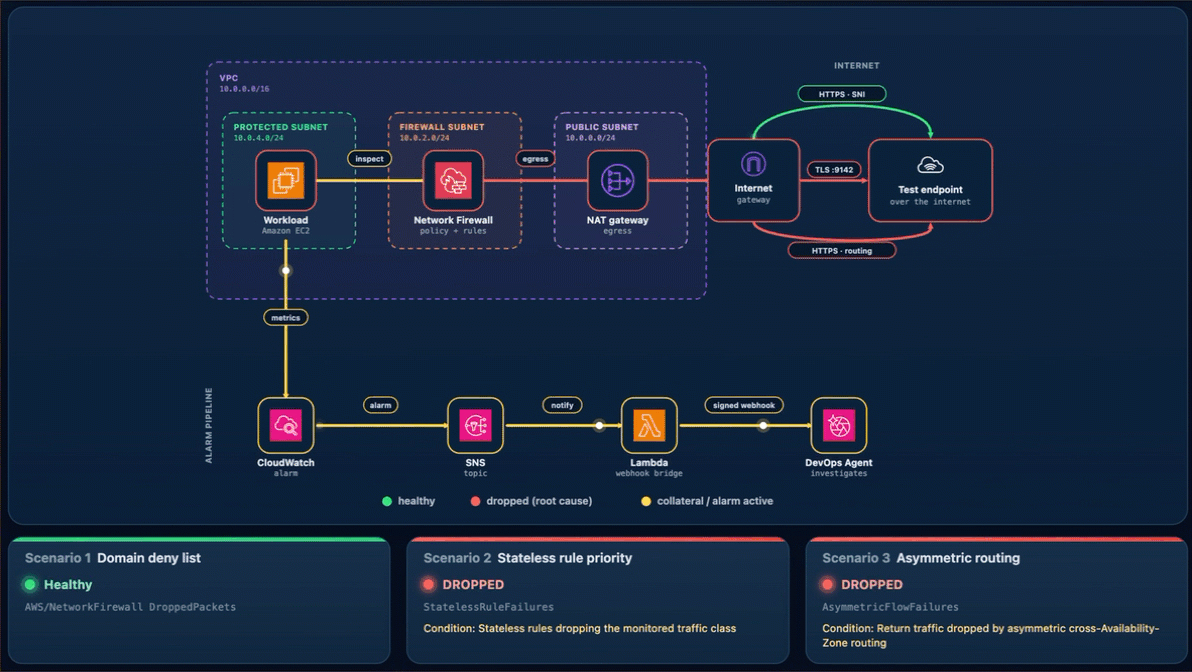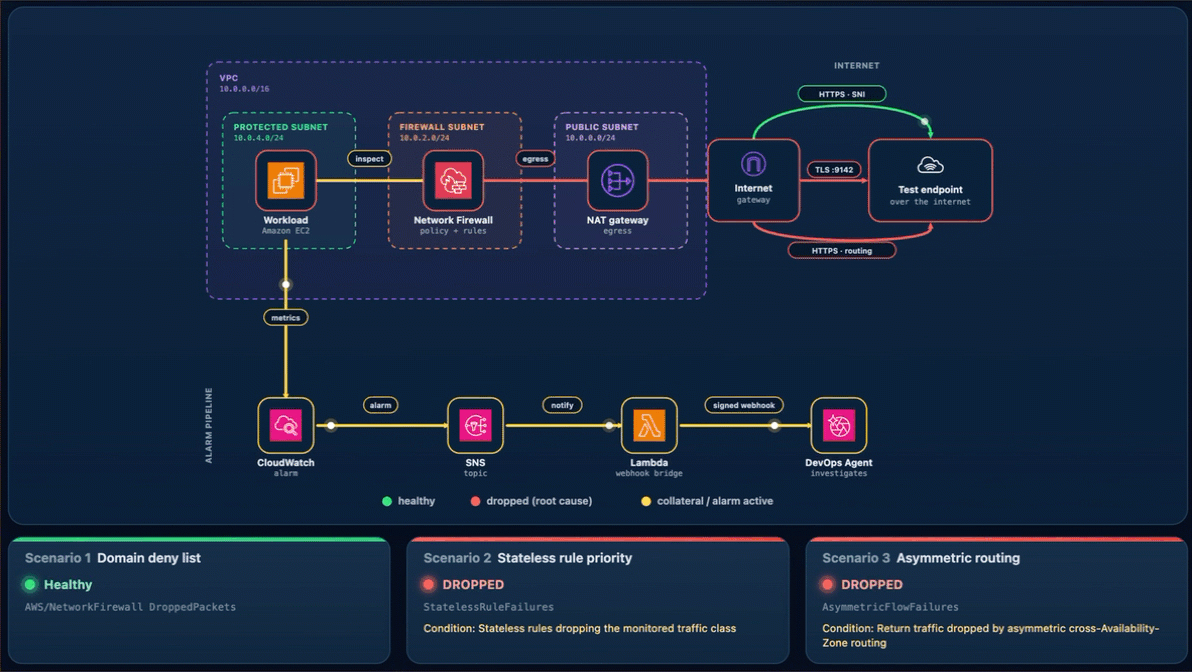
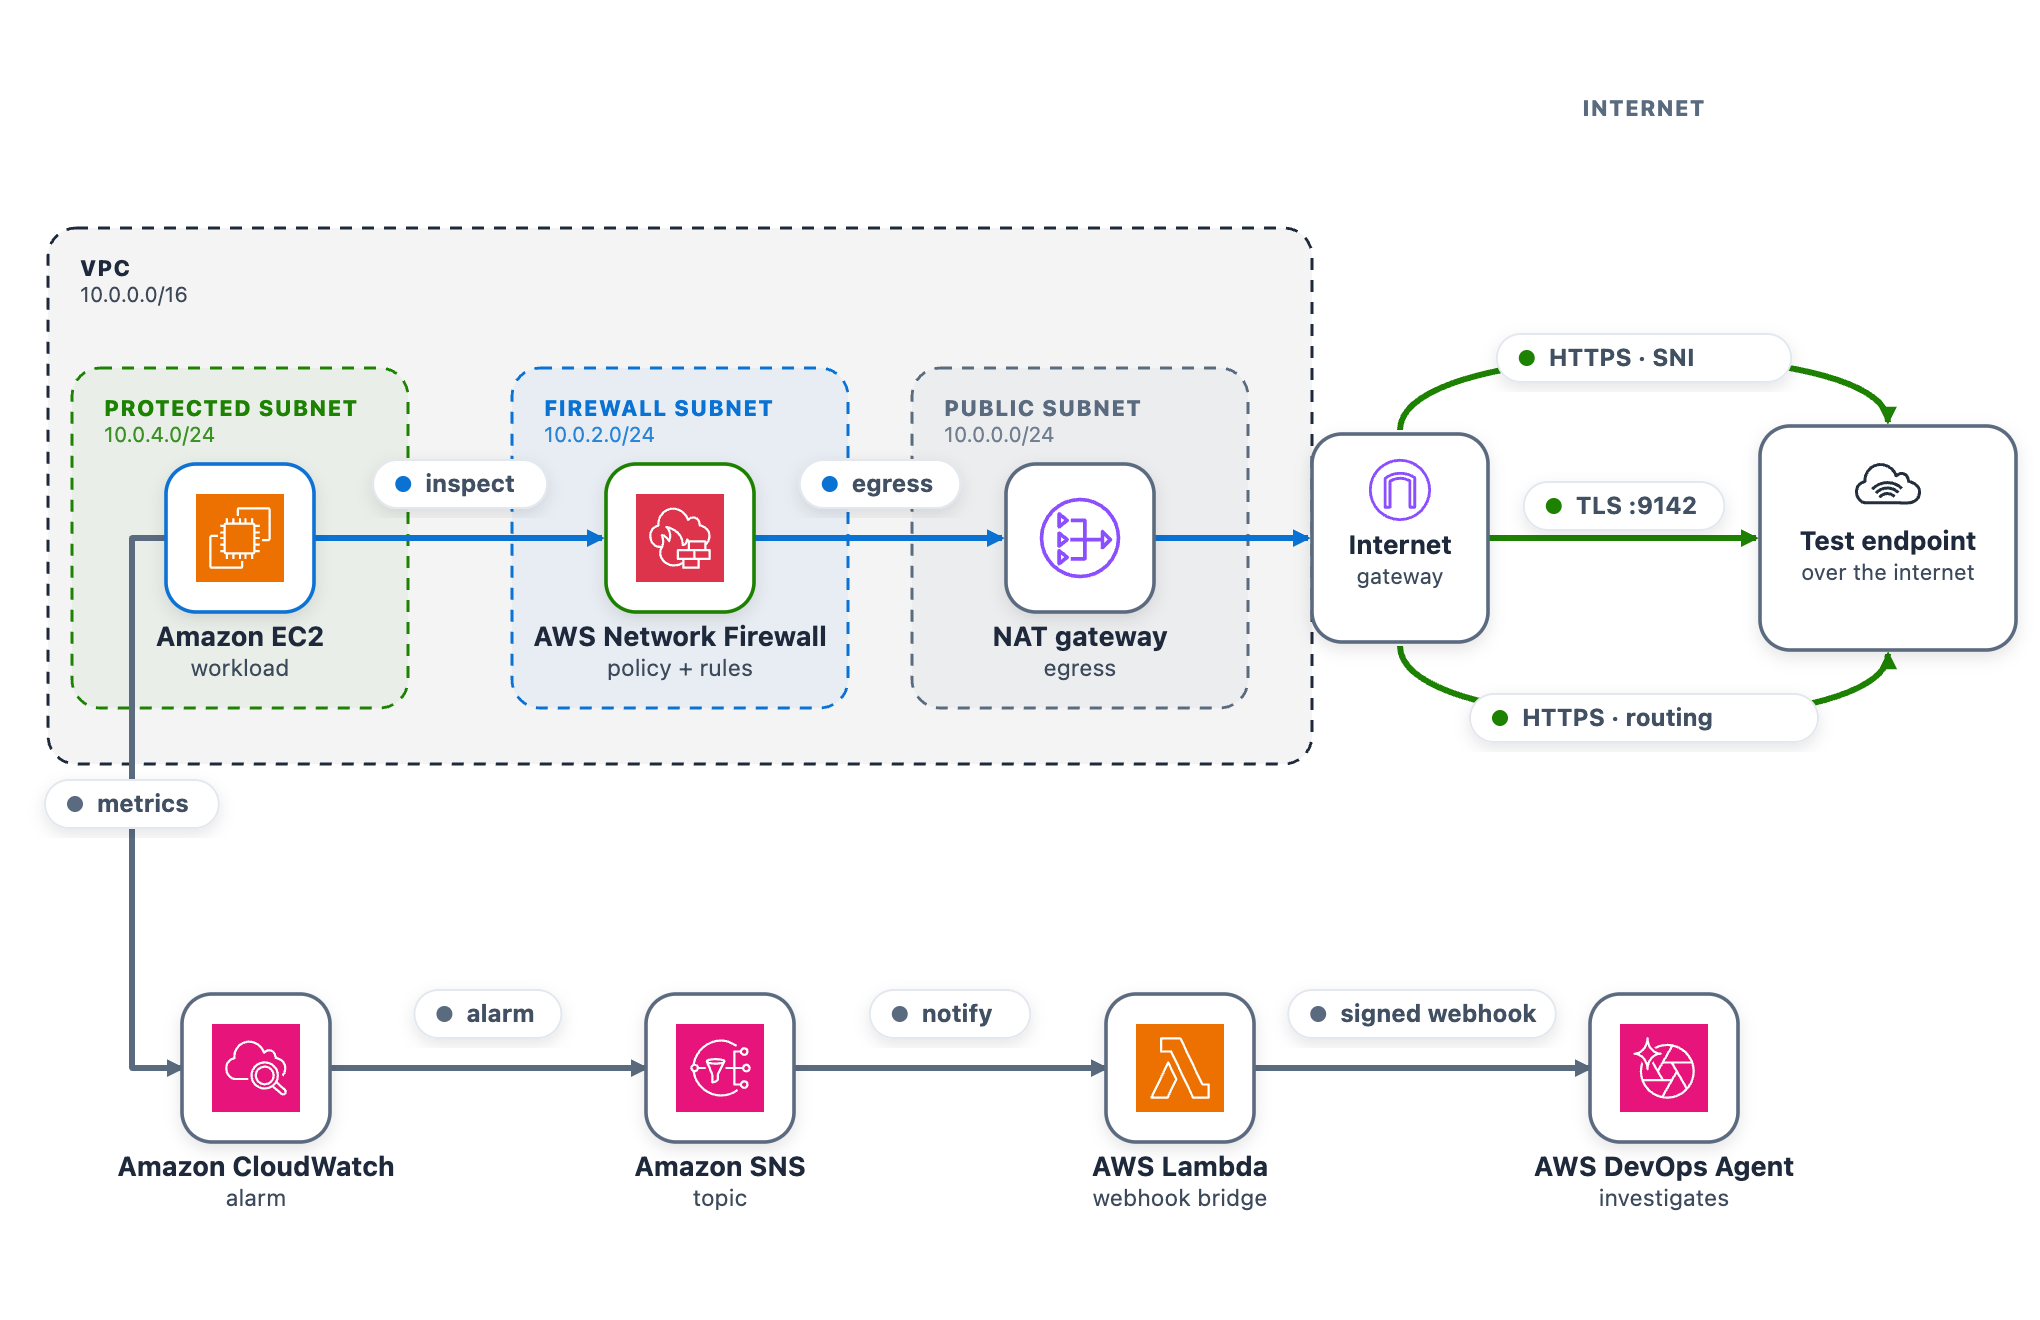
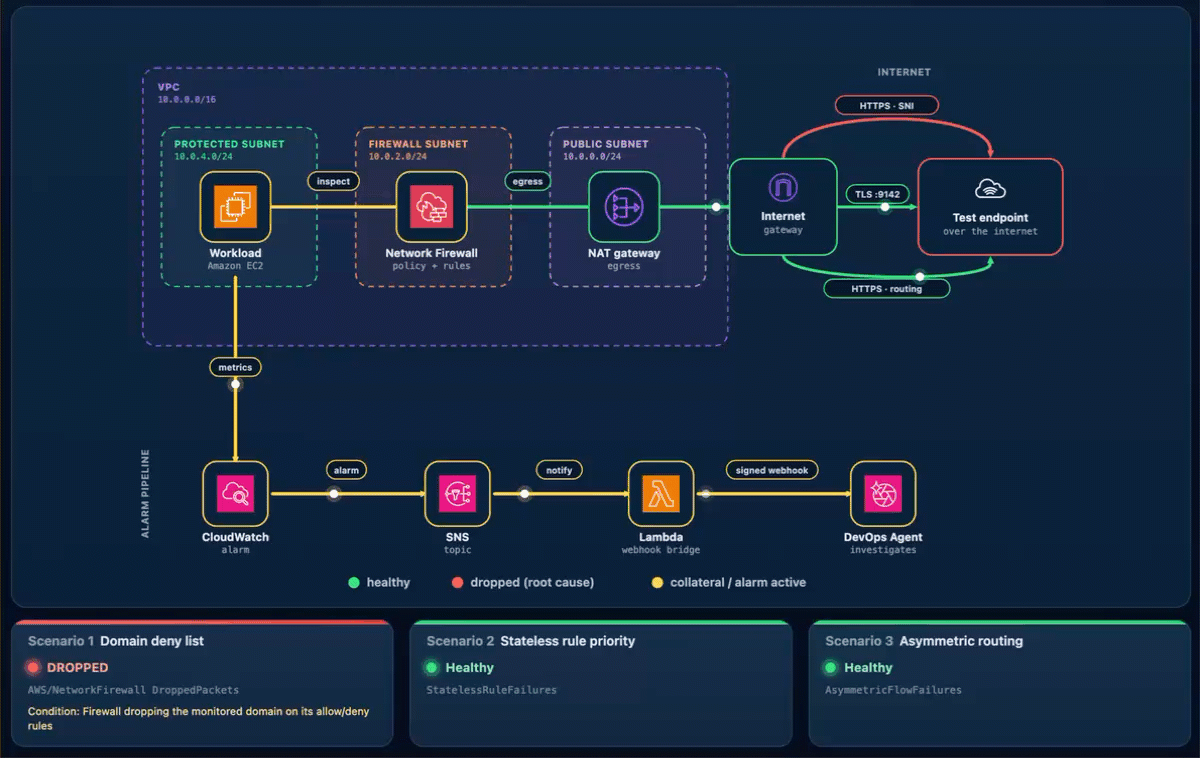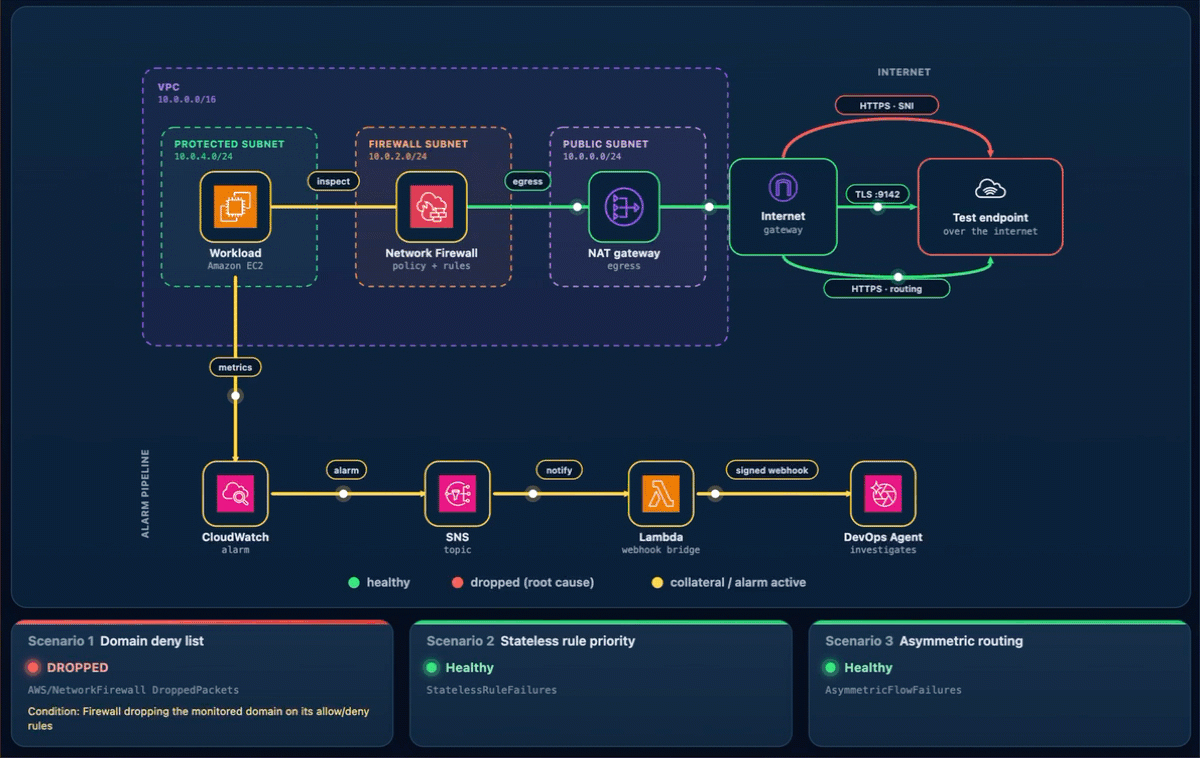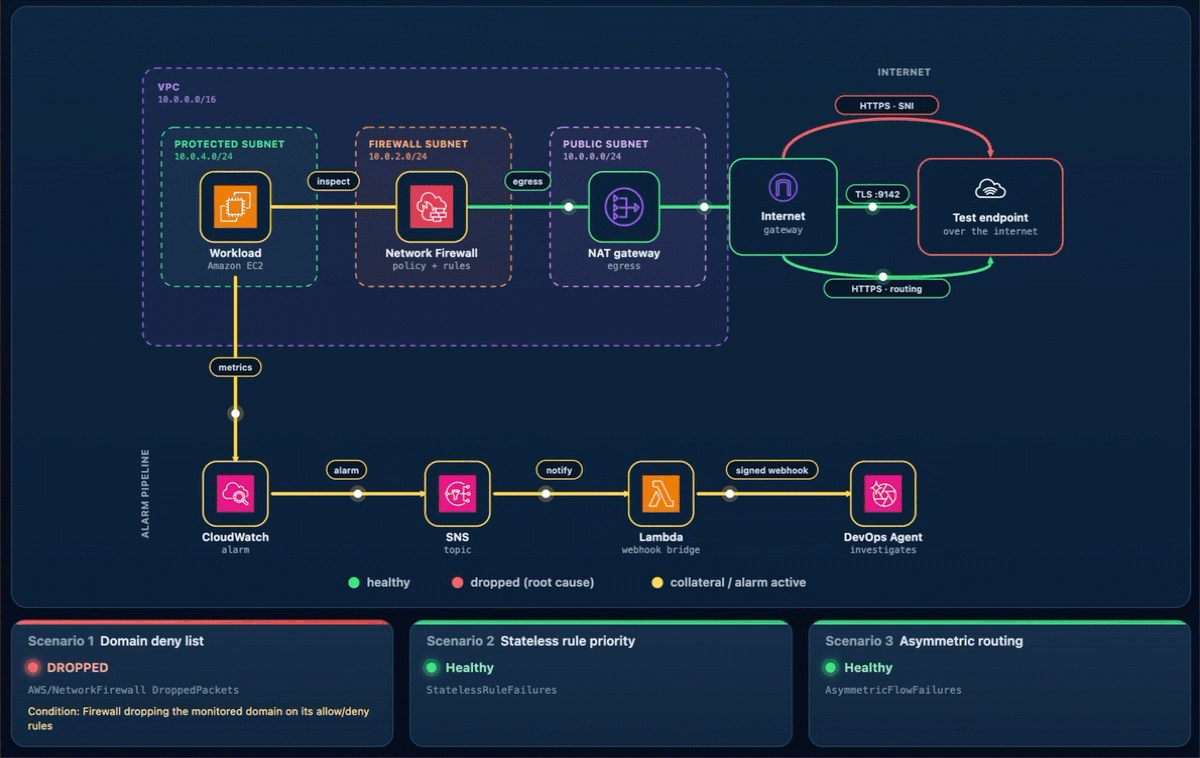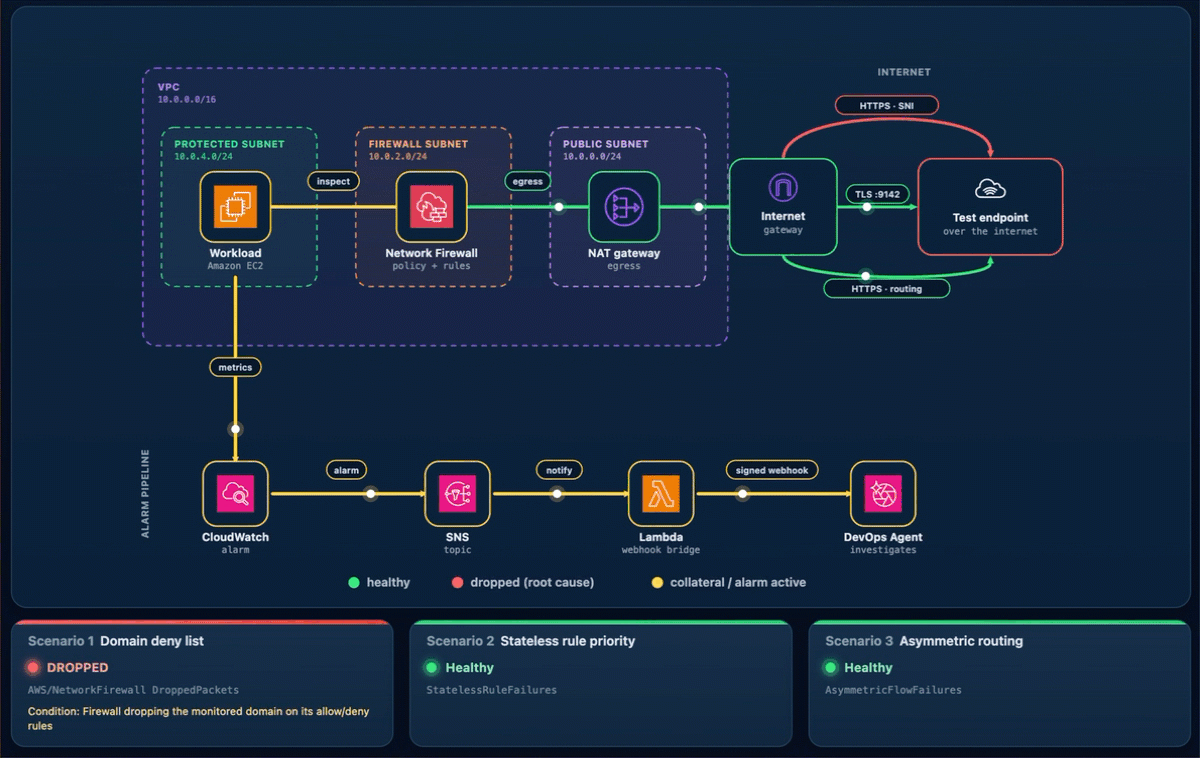
As part of this blog post, we provide a CDK stack that deploys both the AWS DevOps Agent Space and a sample workload used to walk through three separate troubleshooting scenarios. A single t3.micro instance in a protected subnet checks its connectivity to a test endpoint on a continuous loop and publishes results to CloudWatch. Traffic takes the internet egress path through Network Firewall, the NAT gateway, and the internet gateway, so the firewall can intercept or drop it. After completing the walkthrough, you can apply the same troubleshooting techniques with DevOps Agent against your own Network Firewall deployments.

The test endpoint runs in a separate VPC deployed by the same CDK app. It serves HTTPS on port 443 and TCP on port 9142, giving each scenario a different protocol layer to exercise: Scenario 1 targets a TLS connection on 443 (matched by Server Name Indication), Scenario 2 targets a TCP connection on 9142, and Scenario 3 exercises the whole egress path.

A live status page shows one card per scenario plus the network topology. The whole stack deploys from a single CDK app across two Availability Zones, each with a firewall endpoint and NAT gateway, which is what makes Scenario 3 possible.

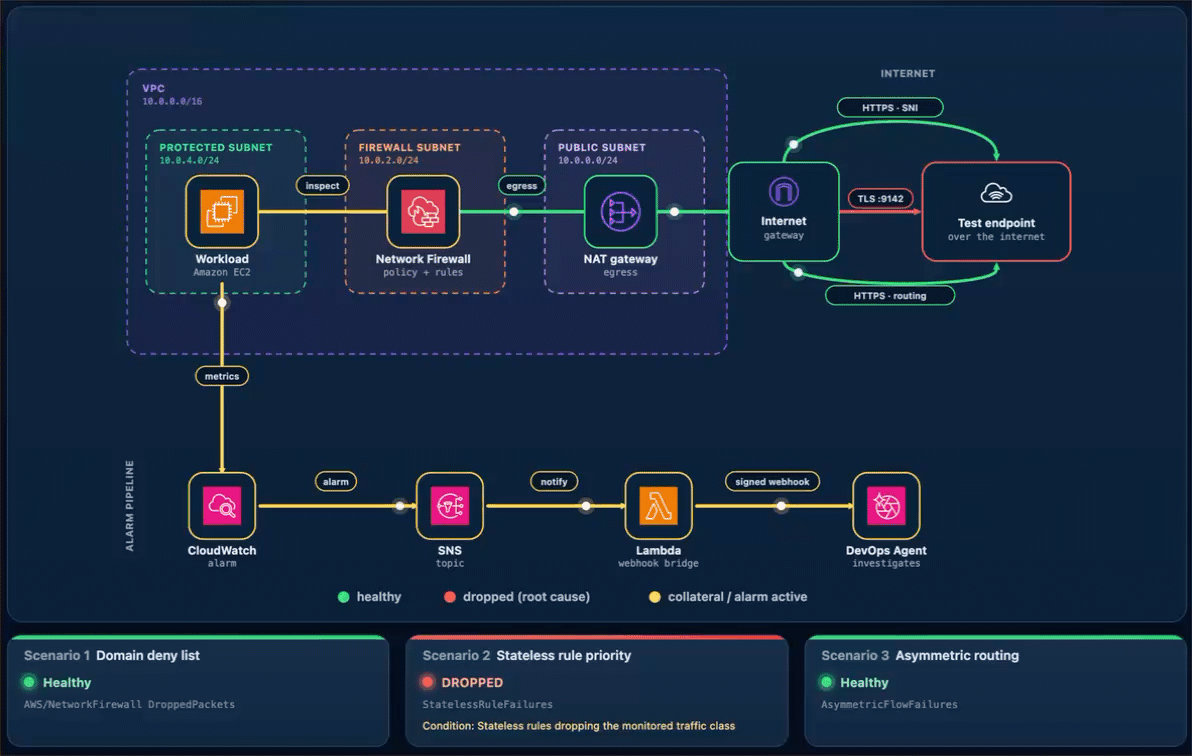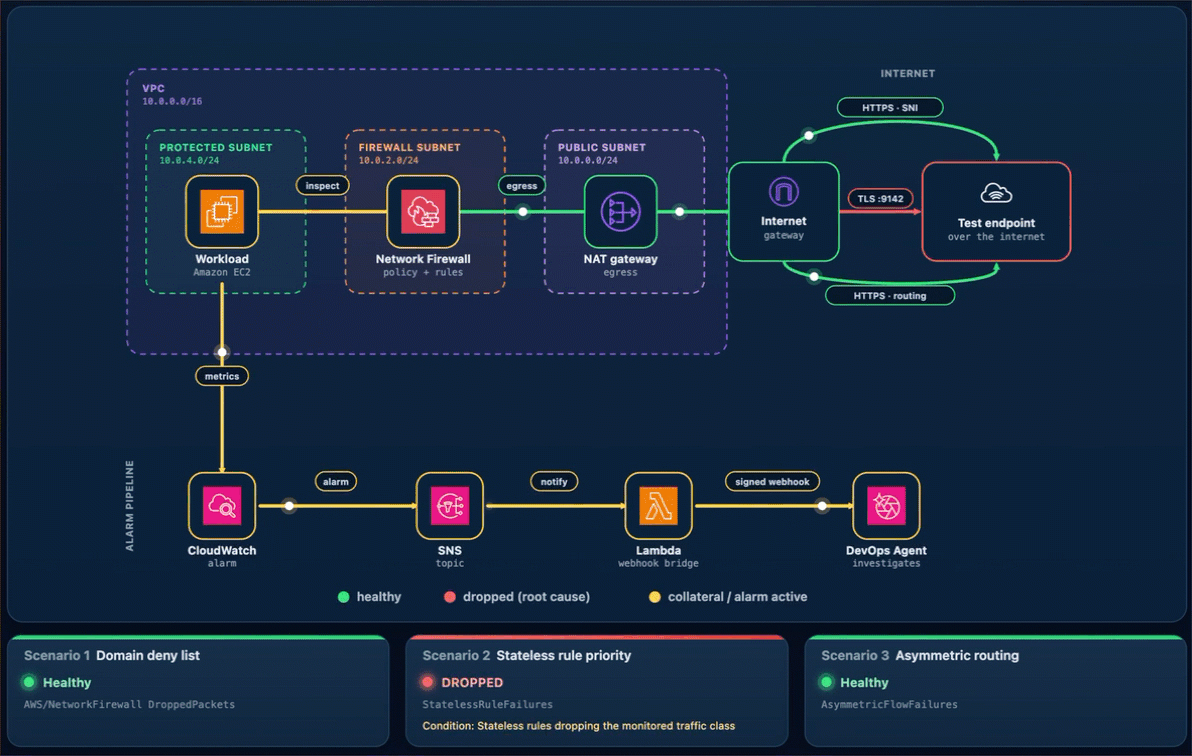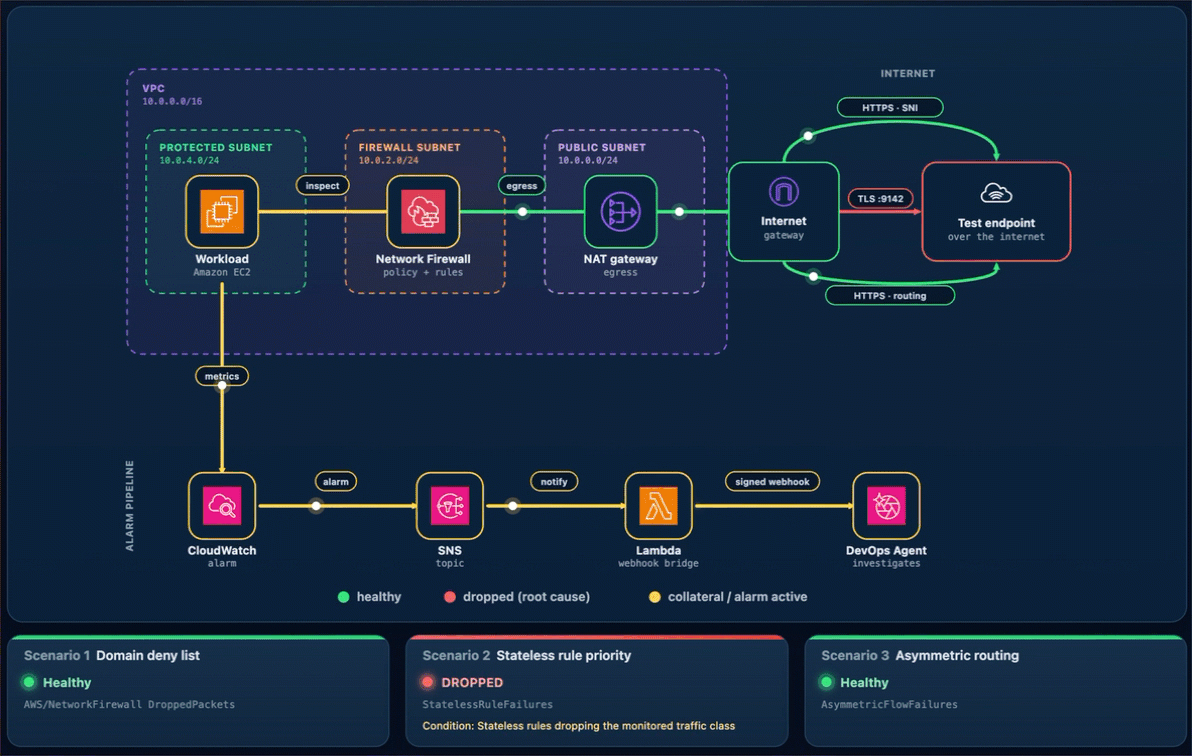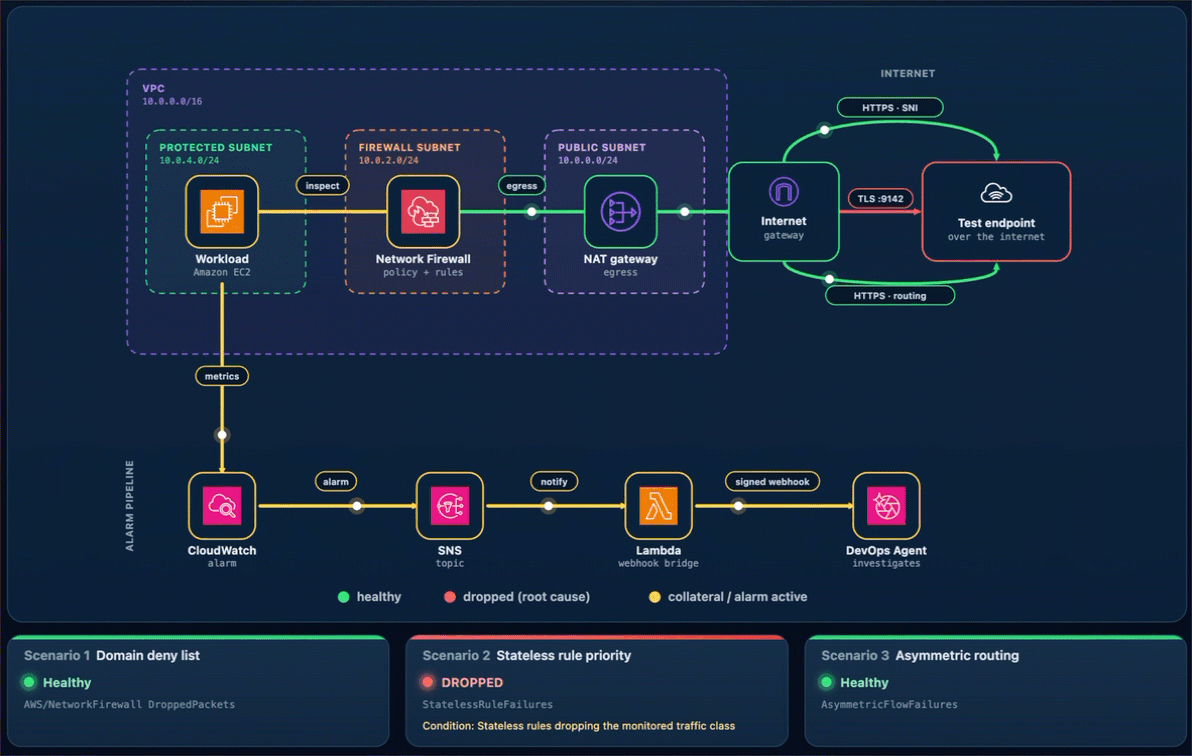
As shown in the following figure, the egress data path runs from the workload through Network Firewall and the NAT and internet gateways to the test endpoint. The alarm pipeline runs from CloudWatch through Amazon Simple Notification Service (Amazon SNS) and the webhook AWS Lambda function to DevOps Agent.

Figure 1: The sample workload

Figure 1: The sample workload

To use this with your own workload, you need a CloudWatch alarm that detects the connectivity problem and the webhook pipeline (SNS topic and Lambda function) that delivers it to DevOps Agent. The agent reads your firewall configuration, logs, and CloudTrail through AWS APIs, so no additional instrumentation is needed on the firewall side.

Prerequisites

To follow along with this post, you need:

Deploy the sample workload

Clone the project and deploy it into us-east-1 with one command (set awsRegion to use another AWS Region).

git clone https://github.com/aws-samples/sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent.git
cd sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent
bash scripts/deploy.sh

The script checks prerequisites, installs dependencies, compiles and tests, and bootstraps the CDK if needed. It then deploys all the stacks from a clean baseline and prints the outputs, including the status-page URL and sign-in details.

  1. Open the status-page link (an https://<random-id>.cloudfront.net address).
  2. Sign in using the username and password provided from the CDK output and confirm all three cards show the green Healthy status.
  3. Keep the page open while you run the scenarios.

Connect AWS DevOps Agent

To connect AWS DevOps Agent to the alarm pipeline

  1. In the AWS DevOps Agent console, open the nf-devops-agent-space Agent Space created by the CDK deployment.
  2. Configure the DevOps Agent webhook and download the CSV file with the webhook URL and signing secret.
  3. On the status page, choose Configure webhook, paste the URL and signing secret, and save. The page writes them to the nf-devops-agent-webhook-credentials AWS Secrets Manager secret, so there is no AWS CLI or console step. Until you set it, the bridge Lambda function sees a placeholder and skips delivery.
  4. Verify the path before you run a scenario. In the Lambda console, open nf-devops-agent-webhook and use the Test tab with this event.
    {
      "Records": [
        {
          "Sns": {
            "Message": "{\"AlarmName\":\"TEST-webhook-verification\",\"AlarmDescription\":\"[TEST] Webhook integration test - not a real alarm.\",\"NewStateValue\":\"ALARM\",\"NewStateReason\":\"[TEST] Manual webhook connectivity test. Safe to ignore.\",\"Region\":\"us-east-1\"}"
          }
        }
      ]
    }

  5. A 200 response confirms the path, and a test investigation appears in the DevOps Agent Operator Web App view.

How the alarm pipeline works

Every scenario reaches DevOps Agent the same way. A CloudWatch alarm moves to ALARM and notifies the SNS topic. Amazon SNS invokes a Lambda function. The function reads the webhook URL and signing secret from Secrets Manager, signs an alarm payload, and POSTs it to the DevOps Agent webhook (as shown in Figure 1). Amazon SNS also provides delivery retries, fan-out to other subscribers, and cross-account publishing.

  • Prebuilt Network Firewall metric (Scenario 1) Alarm-1 watches the DroppedPackets metric, summed across the stateful streams, and triggers when drops rise above a baseline threshold. This requires no workload or custom metric and works on an already-deployed firewall. However, it only tells you that the firewall is dropping packets, not which rule is responsible.
  • Application health metric (Scenarios 2 and 3) Alarm-2 and Alarm-3 watch a custom metric from a connectivity check. Use this for an alarm tied to user-facing impact or to tell one traffic path from another, which requires running a component that emits the metric.
Alarm Source Triggers when
Alarm-1 Native AWS/NetworkFirewall DroppedPackets The firewall’s dropped-packet count rises above the baseline
Alarm-2 Custom application health metric The port 9142 (TCP) connectivity check to the test endpoint is being dropped
Alarm-3 Custom application health metric The cross Availability Zone connectivity check is being dropped

Run the scenarios

Work through each of the scenarios one at a time, following the same cycle. Interrupt network connectivity, watch the alarm trigger, let DevOps Agent investigate, apply the recommended fix, and confirm recovery before moving on.

The status-page cards follow the live CloudWatch alarm state. A card shows a green dot and the word Healthy when its alarm is clear, and a red dot and the word DROPPED when its alarm triggers. In the DROPPED state the card also adds a Condition: line describing what’s being dropped, which isn’t shown when the card is healthy. Network Firewall applies changes to new flows, so a change shows within a minute or two. Recovery comes from the mitigation DevOps Agent recommends, which you review and apply.

Scenario 1. Domain deny list blocking a legitimate endpoint

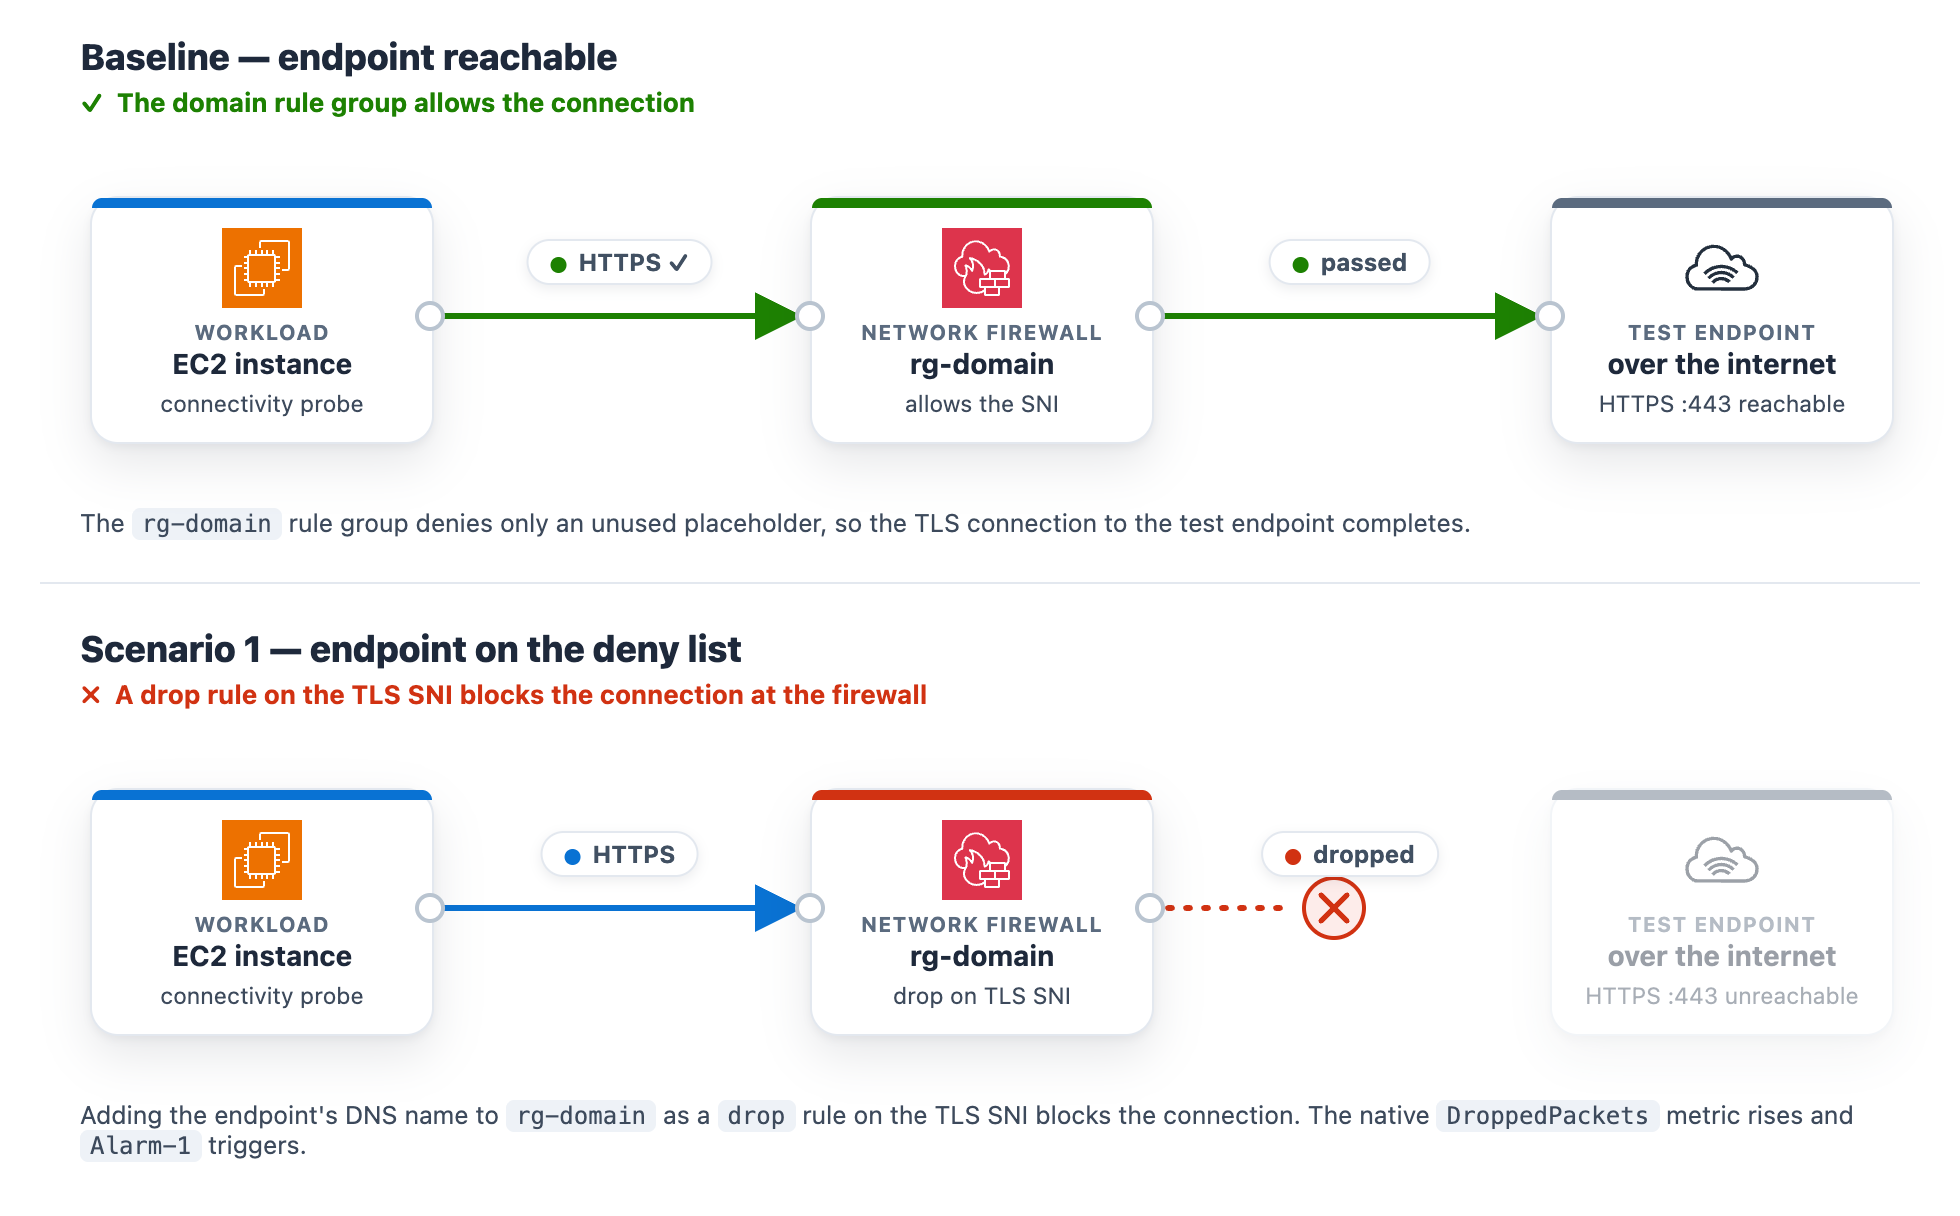
At baseline, the rg-domain Suricata domain rule group denies only an unused placeholder, so the test endpoint stays reachable. The rule group inspects the TLS Server Name Indication (SNI) on each outbound connection and drops any that matches a denied domain. The exact rule syntax and console steps follow.

To add the domain deny rule

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-domain rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. The rules box already contains two baseline placeholder rules (they match blocked.placeholder.invalid, so nothing real is denied). Leave those in place. Find the <app-endpoint-dns> value for Scenario 1 in the deployment script output (a Nework Load Balancer (NLB) DNS name such as NfTest-AppNl-a1b2C3dEf4G5-1234abcd5678efgh.elb.us-east-1.amazonaws.com). On a new line below the existing rules, add a drop rule that matches that DNS name on the TLS SNI, then choose Save.
    drop tls $HOME_NET any -> $EXTERNAL_NET any (ssl_state:client_hello; tls.sni; content:"<app-endpoint-dns>"; startswith; nocase; endswith; msg:"S1 domain denylist"; flow:to_server, established; sid:2000002; rev:1;)

  6. After saving, the rules box holds all three lines. The two placeholders remain, plus the new drop rule for the endpoint DNS name (note the distinct sid 2000002).
Figure 2: Scenario 1 – Firewall rule change blocking the connection

Figure 2: Scenario 1 – Firewall rule change blocking the connection

What happens. The workload’s HTTPS check to the test endpoint times out, the “AWS/NetworkFirewall DroppedPackets metric climbs above baseline, and Alarm-1 moves to ALARM. The Scenario 1 card reads DROPPED (with the condition Firewall dropping the monitored domain on its allow/deny rules), while the Scenario 2 and Scenario 3 cards stay Healthy (Figure 3). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the HTTPS · SNI line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Let DevOps Agent investigate. The agent runs several lines of investigation in parallel and correlates them:

  1. Reads the DroppedPackets metric and correlates the spike with a simultaneous drop in passed packets, confirming the firewall is actively blocking traffic.
  2. Reads the ALERT log and finds the workload’s TLS connections to the test endpoint blocked by the S1 domain denylist rule.
  3. Compares the current state against a baseline window, where the same endpoint was reachable with no alerts, which shows the block is new.
  4. Searches CloudTrail and surfaces the UpdateRuleGroup call that added the deny rule, identifying the user, role, and timestamp approximately one minute before the drops began.
  5. Reports the root cause as that manual rule-group change. Recommends removing the deny entry or adding an allow exception and enabling FirewallPolicyChangeProtection to prevent unauthorized changes.
  6. Presents this as a plan you review and apply, not an automatic change.

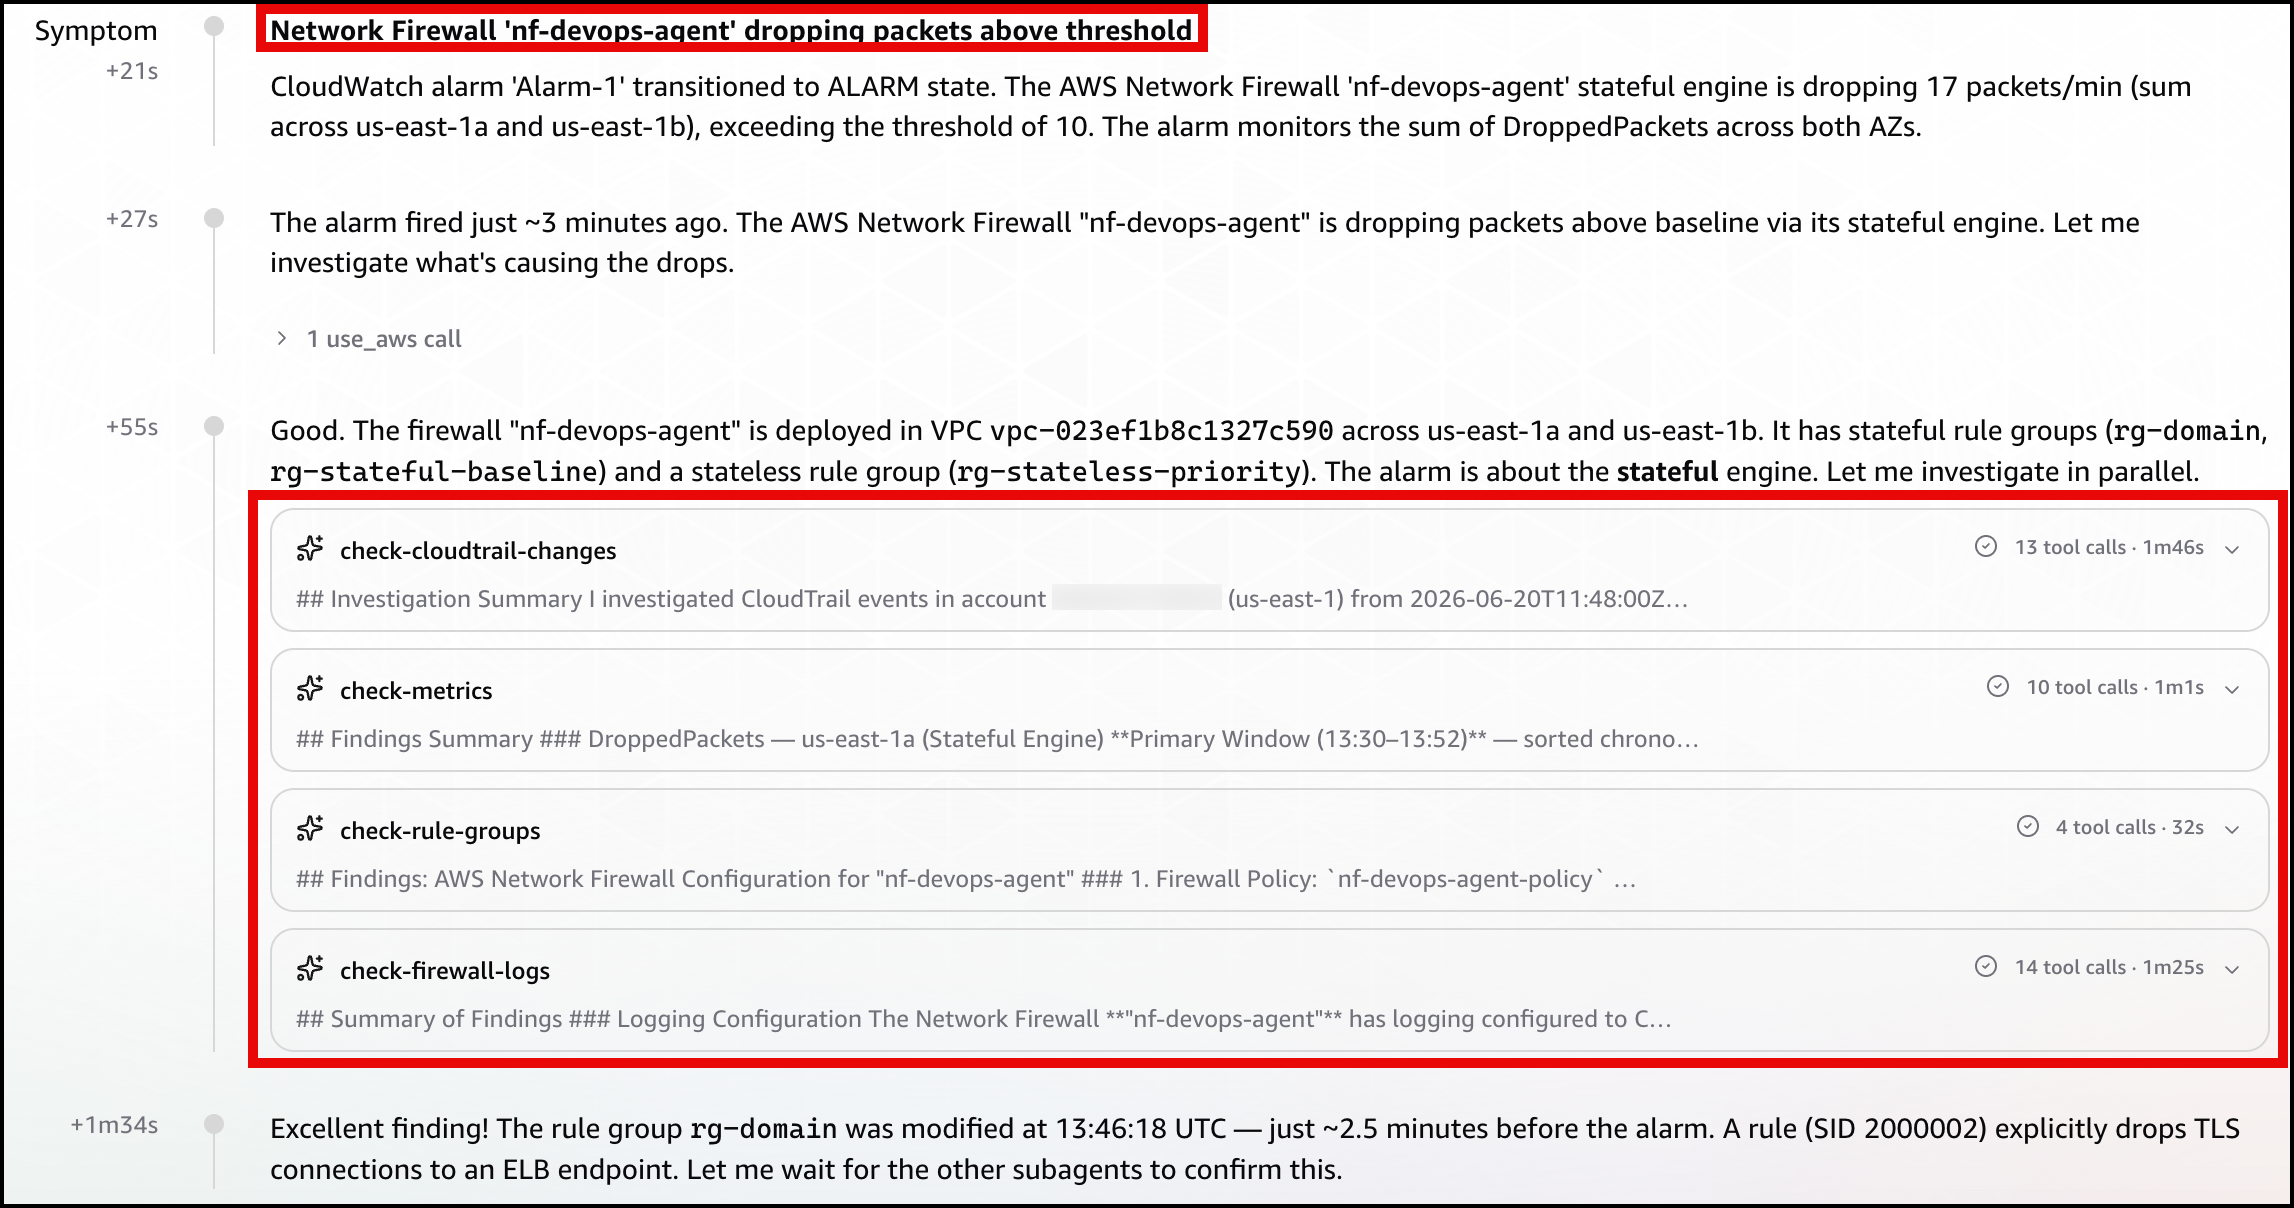
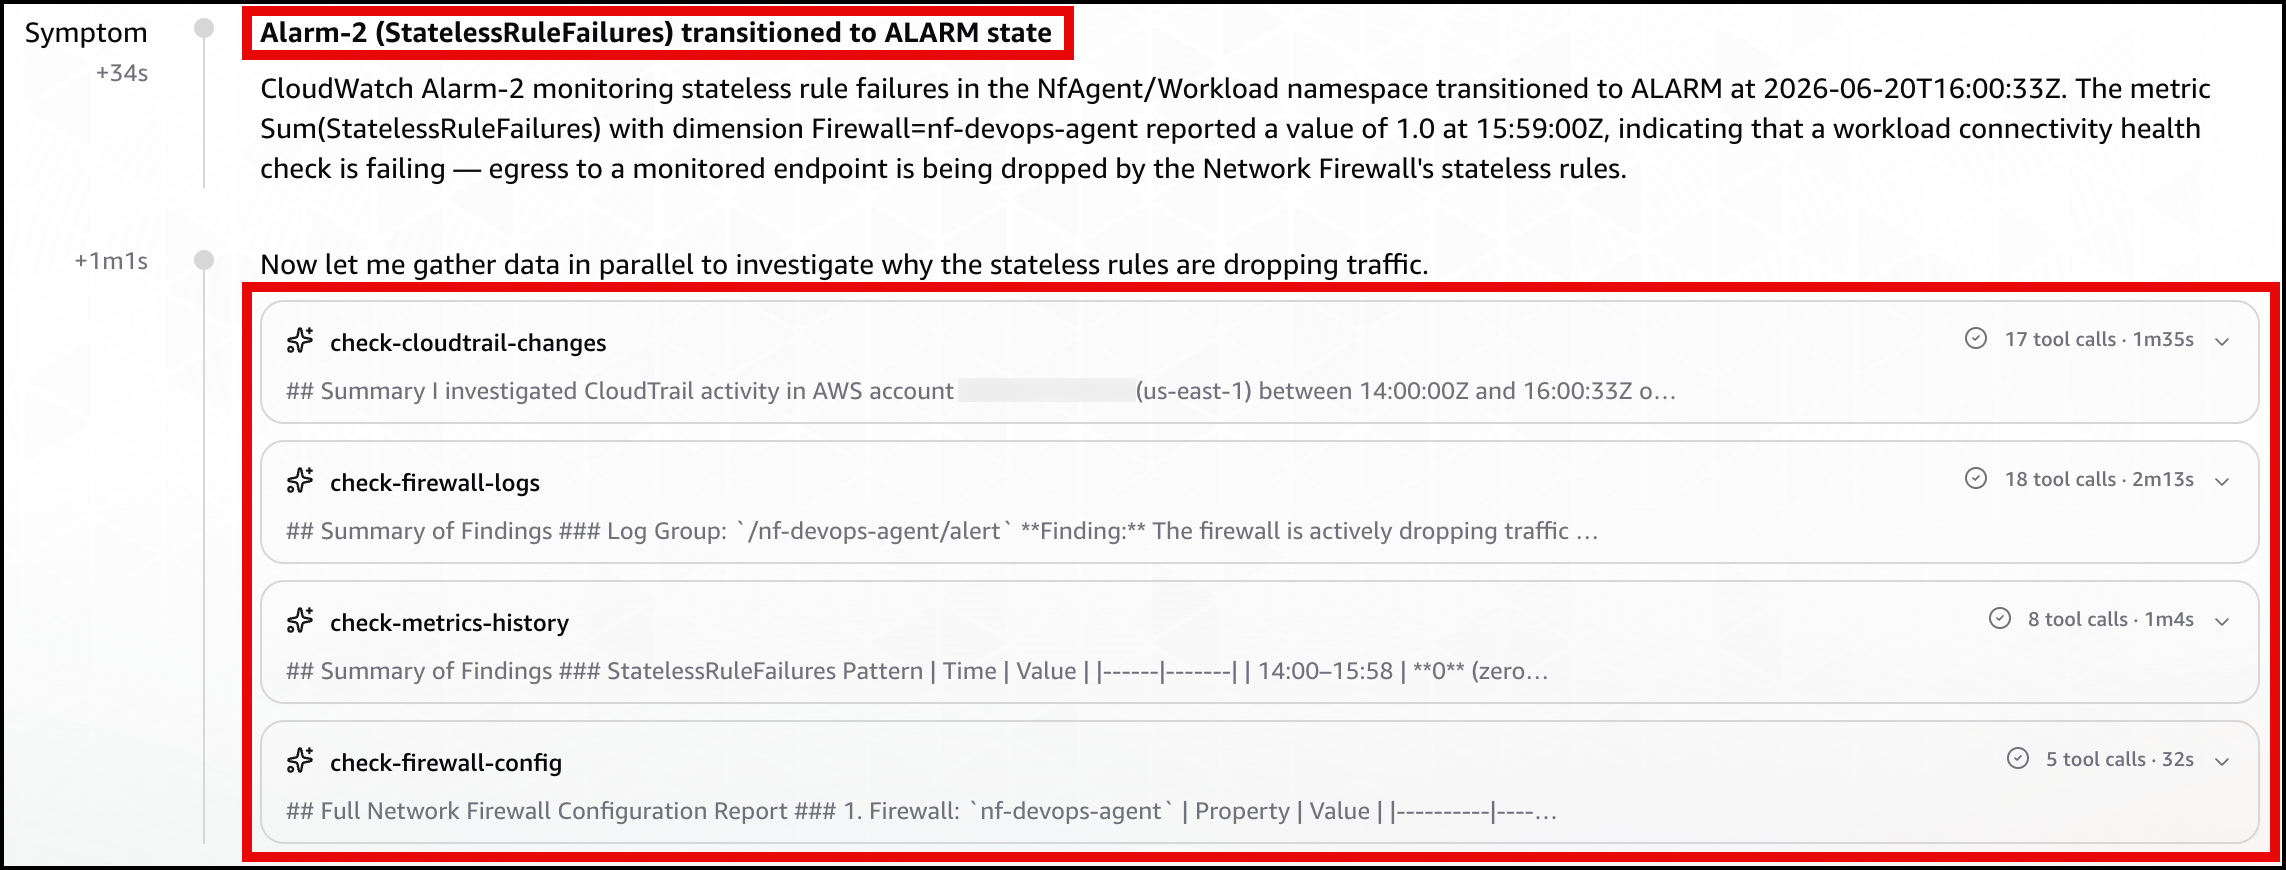
In the DevOps Agent Operator Web App view, the agent first restates the Alarm-1 trigger and confirms the firewall is dropping packets above the threshold (Figure 4).

Figure 4: Scenario 1 – The symptom

Figure 4: Scenario 1 – The symptom

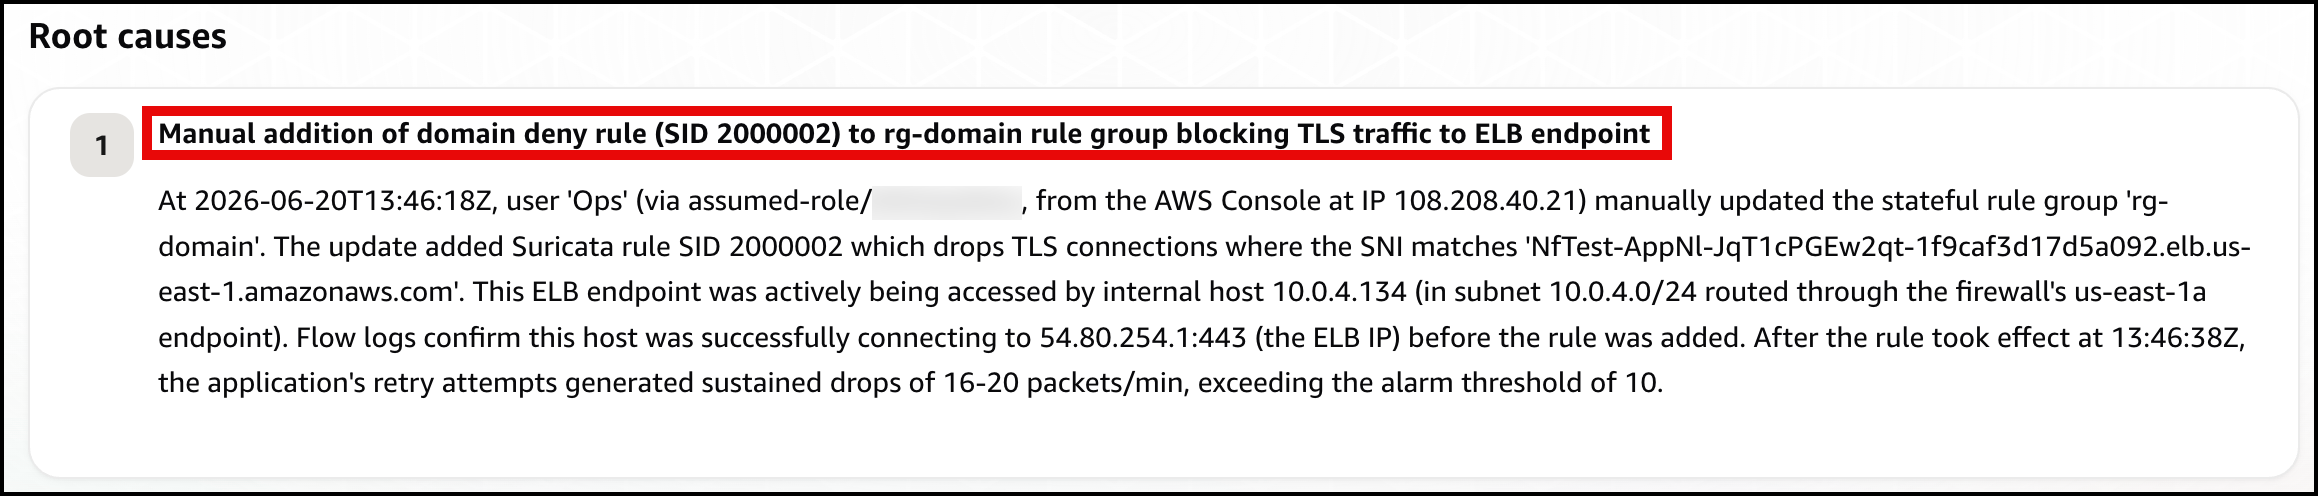
Next, the agent identifies the root cause: a manual update to the rg-domain rule group that added a domain deny rule (SID 2000002) shortly before the alarm fired, blocking TLS connections to the ELB endpoint (Figure 5).

Figure 5: Scenario 1 – The root cause

Figure 5: Scenario 1 – The root cause

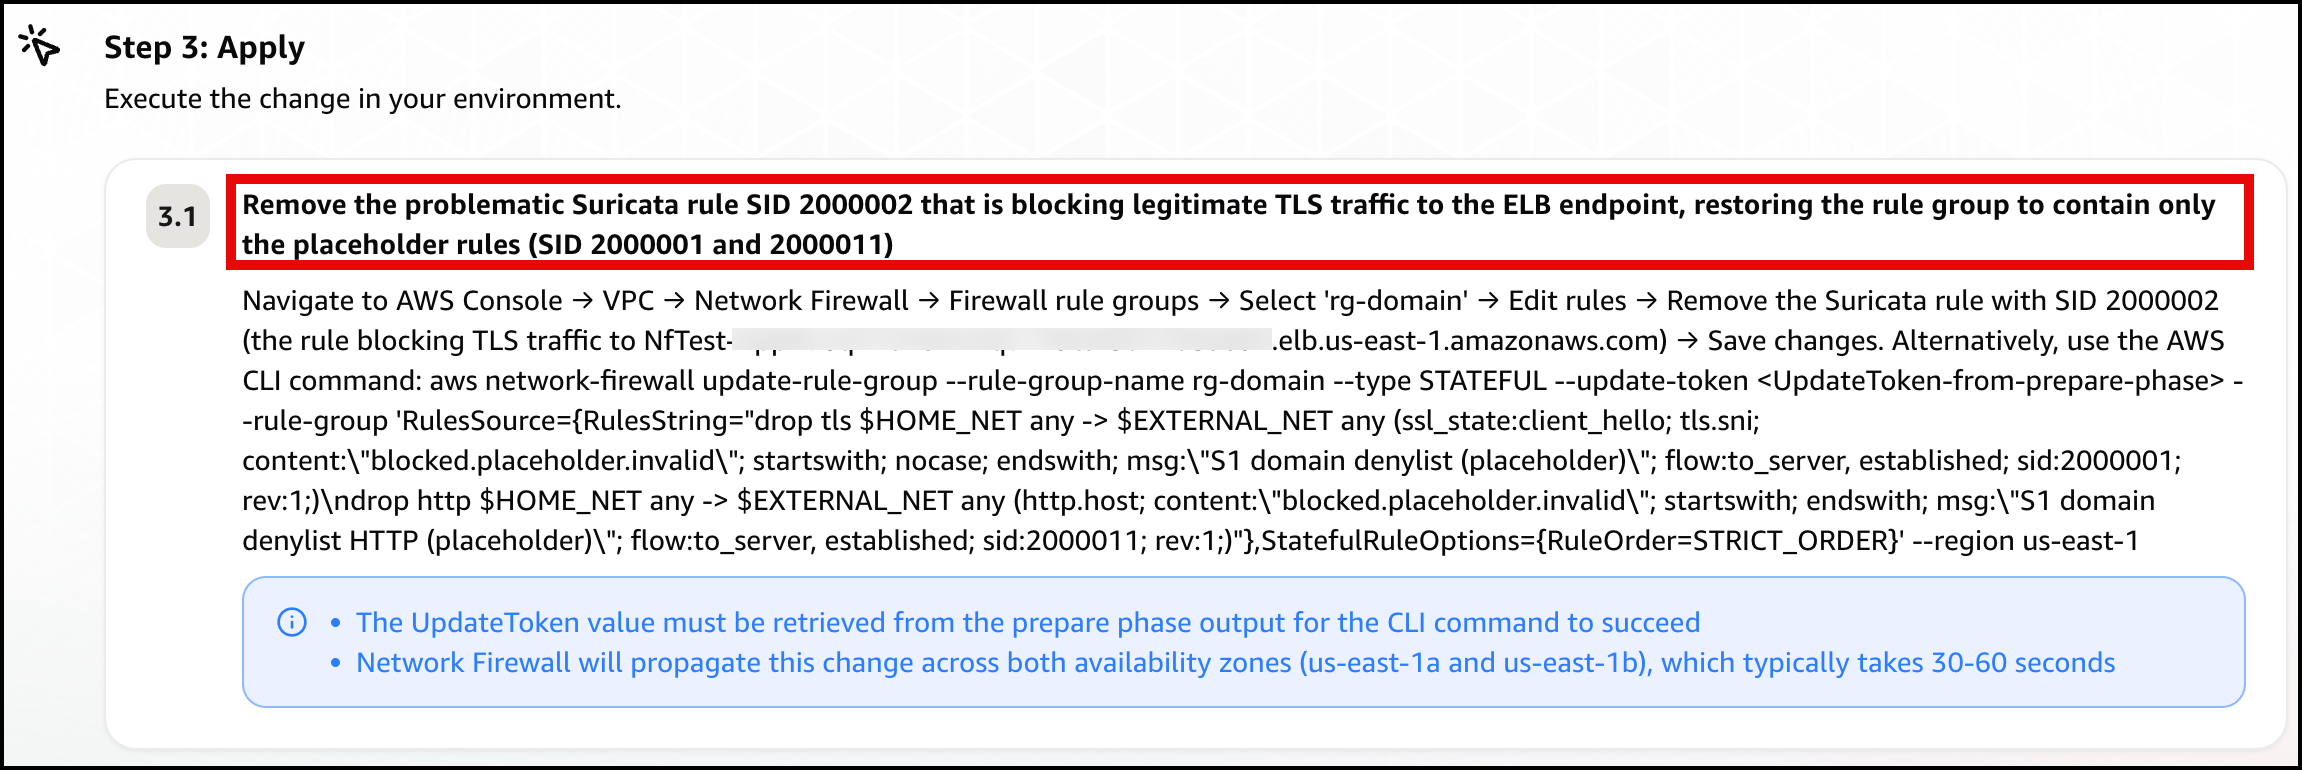
Finally, the agent presents a mitigation plan, recommending you remove the problematic deny rule (SID 2000002) to restore connectivity (Figure 6).

Figure 6: Scenario 1 – The mitigation plan

Figure 6: Scenario 1 – The mitigation plan

Note: In a real-world environment, this type of rule typically exists for a reason. Before removing it, verify whether it was intentional but scoped too broadly. If so, refine the rule to block only unauthorized endpoints rather than removing it entirely.

Confirm recovery. Apply the change the agent recommends. After the deny entry is gone, DroppedPackets falls back to baseline, Alarm-1 clears, and the card returns to green. Move on to Scenario 2.

Scenario 2. Stateless rule priority misconfiguration

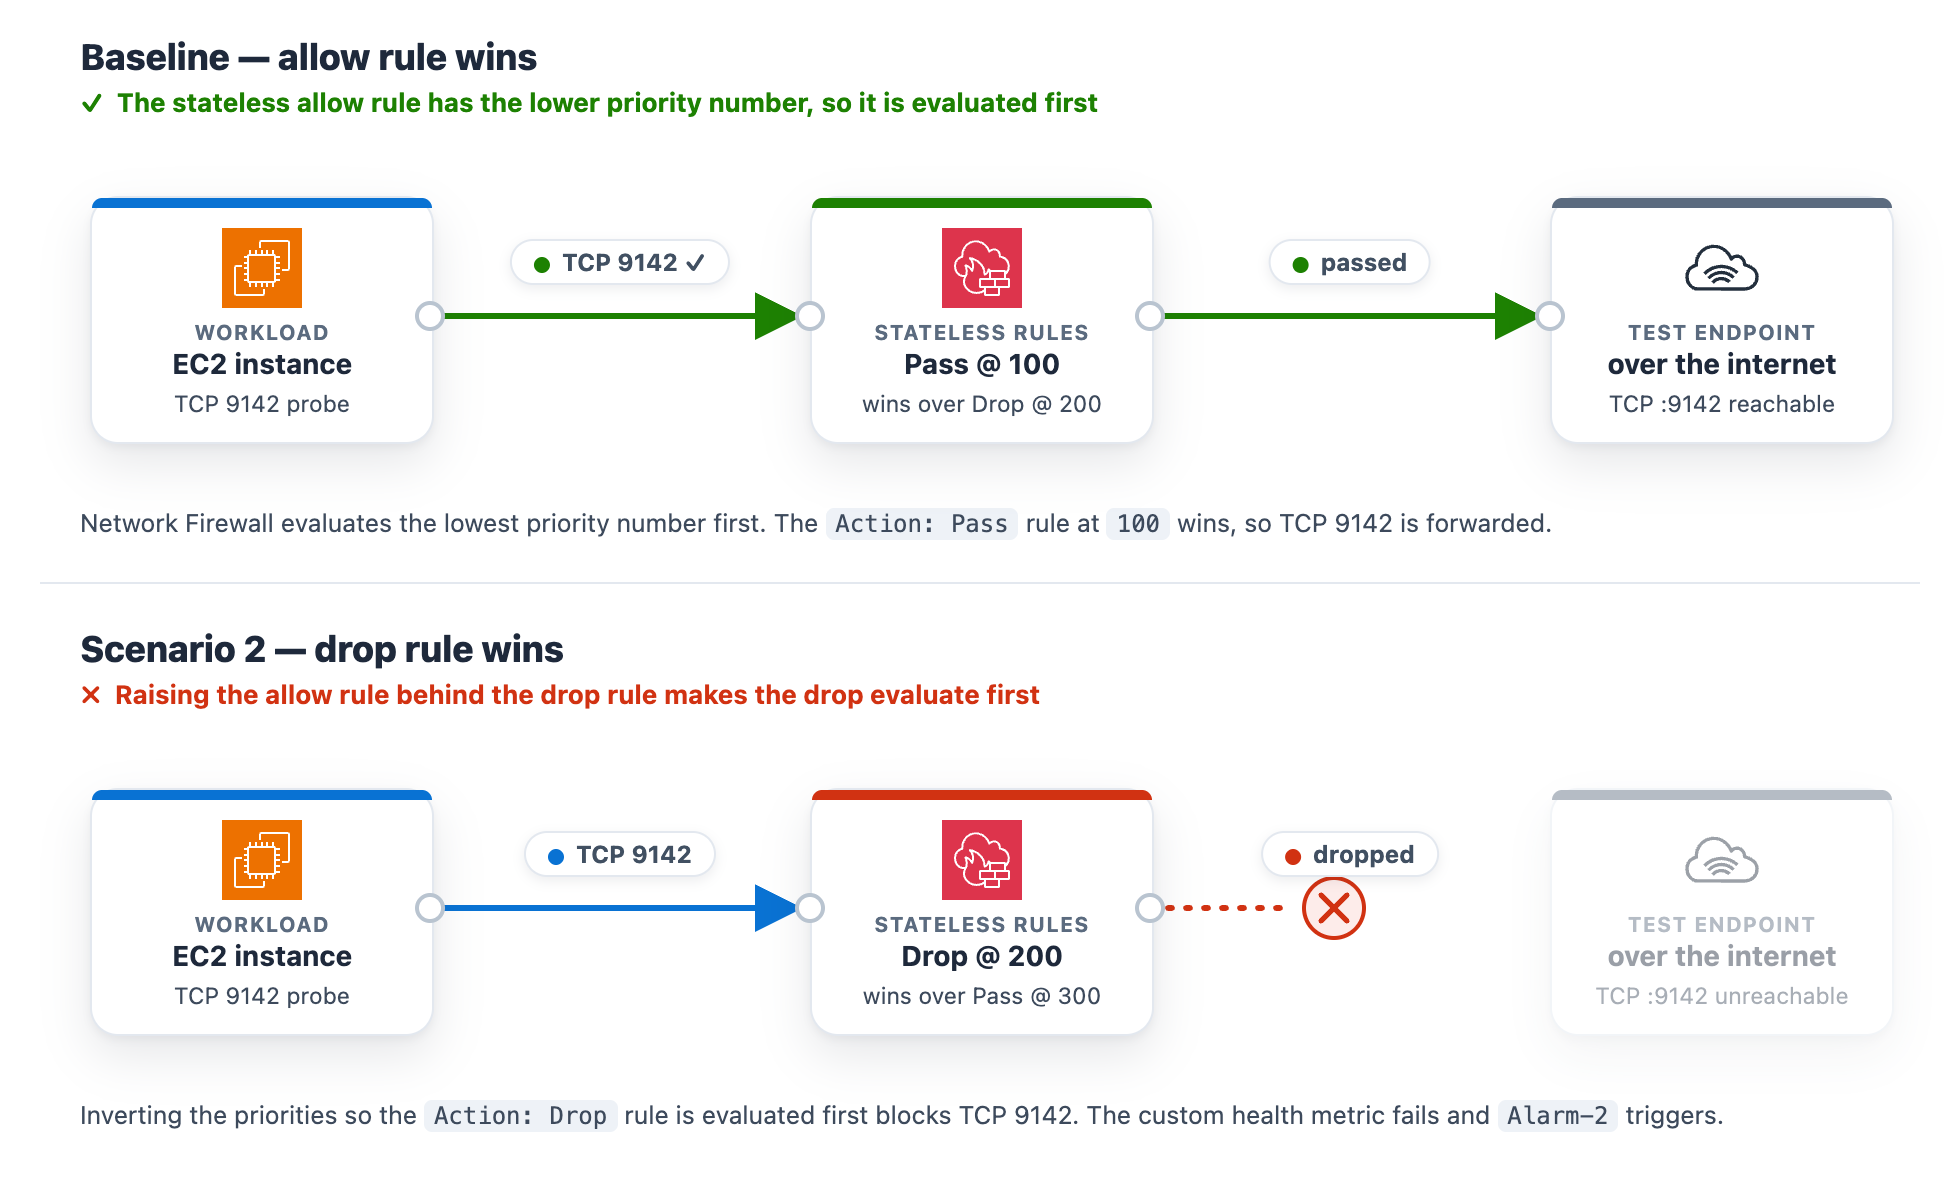
At baseline, the rg-stateless-priority stateless rule group keeps the allow rule at priority 100 and the drop rule at 200 for the test class, TCP destination port 9142. The workload opens a TCP connection to the test endpoint on this port. Lower priority numbers evaluate first, so the allow rule wins. This scenario uses port 9142 instead of 443 to demonstrate a stateless rule, which matches on the packet’s 5-tuple (protocol, ports, addresses) rather than application content.

Introduce the change. Invert the two rule priorities so the drop rule evaluates before the allow rule. This is the kind of change a rushed rule edit can introduce.

To invert the stateless rule priorities

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-stateless-priority rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. Raise the (Action: Pass) rule’s priority number so it sits after the (Action: Drop) rule, then choose Save. For example, change the (Action: Pass) rule from 100 to 300 (any number higher than the drop rule’s 200 works). You only need to move one rule, and using 300 avoids a clash with the drop rule that already sits at 200. Network Firewall evaluates the lowest priority number first, so the (Action: Drop) rule at 200 now wins for this traffic class, ahead of the (Action: Pass) rule at 300.
Figure 7: Scenario 2 – Rule priority change blocking the traffic class

Figure 7: Scenario 2 – Rule priority change blocking the traffic class

What happens. The drop rule now wins, the TCP connection to the test endpoint on port 9142 times out, the StatelessRuleFailures metric climbs above baseline, and Alarm-2 moves to ALARM. The Scenario 2 card reads DROPPED (with the condition Stateless rules dropping the monitored traffic class), while the Scenario 1 and Scenario 3 cards stay Healthy (Figure 8). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the TLS :9142 line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 8: Scenario 2 active

Figure 8: Scenario 2 active

Let DevOps Agent investigate. A stateless drop happens before traffic reaches the stateful inspection engine, so it produces no ALERT log entries. The agent turns to configuration and flow logs instead:

  1. Reads the stateless rule group state and finds the drop rule at the lower priority number, ahead of the pass rule, so the drop evaluates first.
  2. Reads the flow logs and sees passed packets drop to zero within a minute of the change.
  3. Searches CloudTrail and surfaces the UpdateRuleGroup call that inverted the priorities, identifying the user, role, and timestamp about a minute before the alarm.
  4. Reports the root cause as that priority inversion. Recommends removing the redundant drop rule and managing the rule group through infrastructure-as-code (IaC) to prevent manual misconfigurations.
  5. Presents this as a plan you review and apply, not an automatic change.

In the DevOps Agent Operator Web App view, the agent first restates the Alarm-2 trigger and confirms that a workload connectivity health check is failing because the firewall’s stateless rules are dropping egress (Figure 9).

Figure 9: Scenario 2 – The symptom

Figure 9: Scenario 2 – The symptom

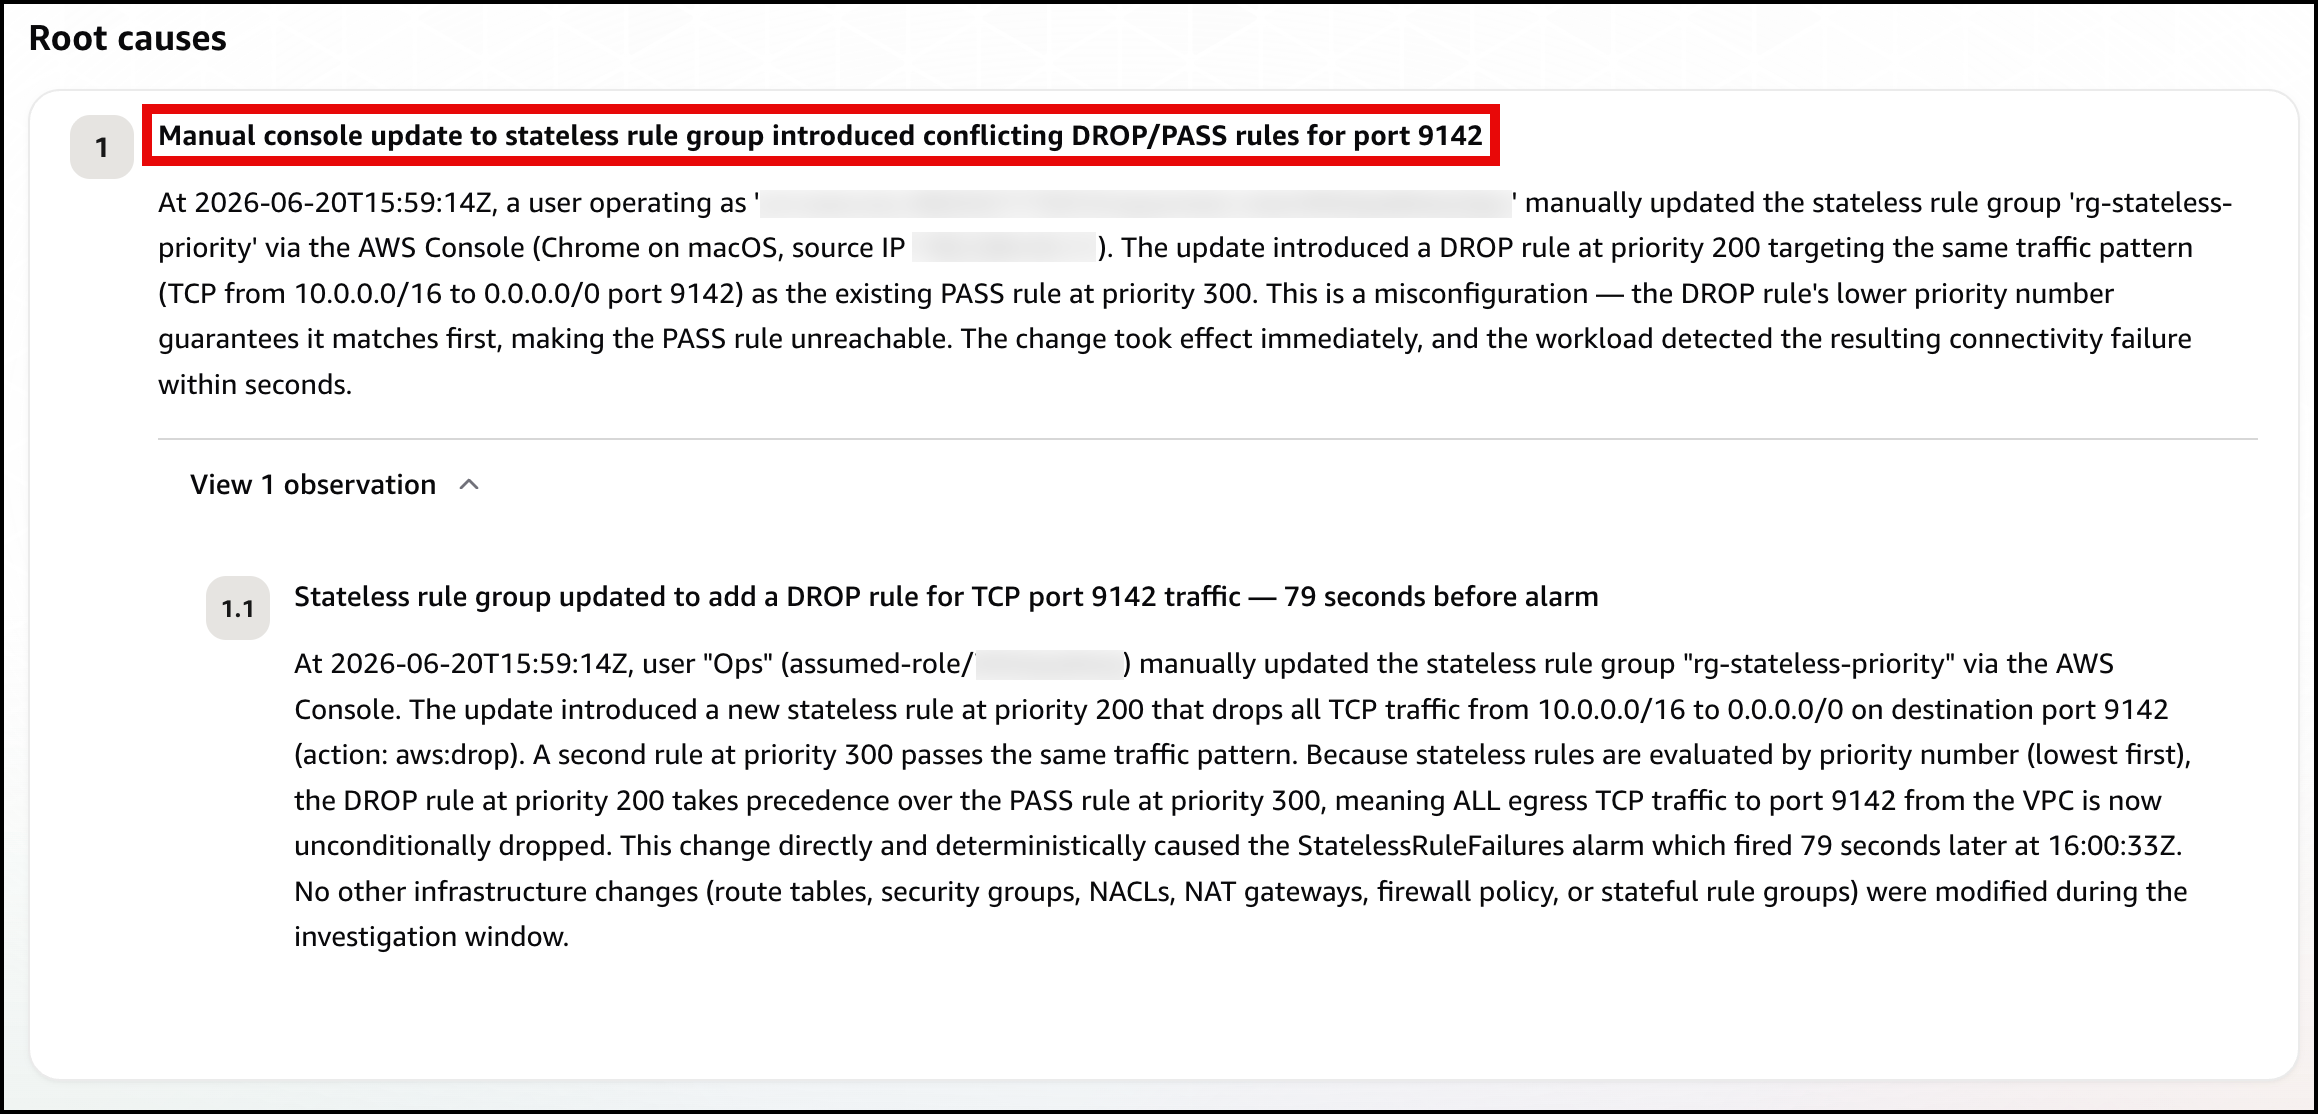
Next, the agent identifies the root cause, using the rule-group state and CloudTrail to pinpoint the conflicting DROP/PASS rules, where the new DROP rule’s lower priority number makes it match first (Figure 10).

Figure 10: Scenario 2 – The root cause

Figure 10: Scenario 2 – The root cause

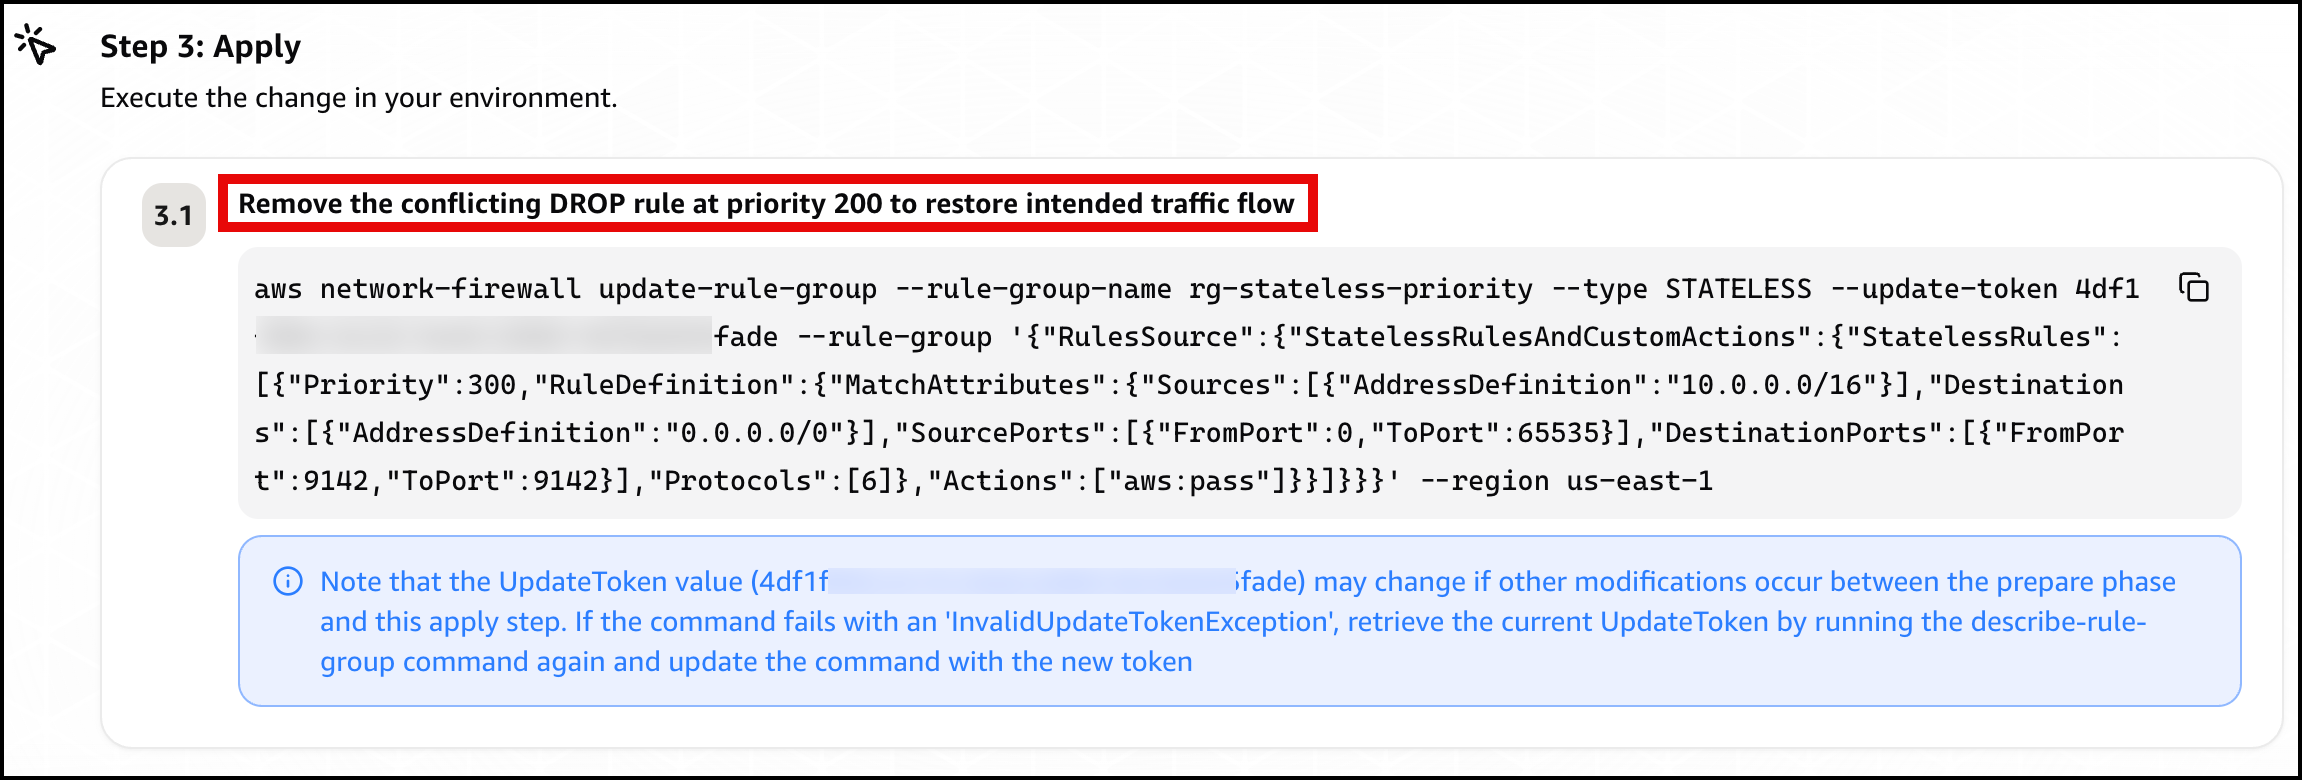
Finally, the agent presents a mitigation plan, recommending you remove the conflicting DROP rule at priority 200 to restore traffic flow (Figure 11).

Figure 11: Scenario 2 – The mitigation plan

Figure 11: Scenario 2 – The mitigation plan

Confirm recovery. Apply the change the agent recommends. After the allow rule is ahead of the drop rule again, Alarm-2 clears and the card returns to green. Move on to Scenario 3.

Scenario 3. Asymmetric cross Availability Zone routing drop

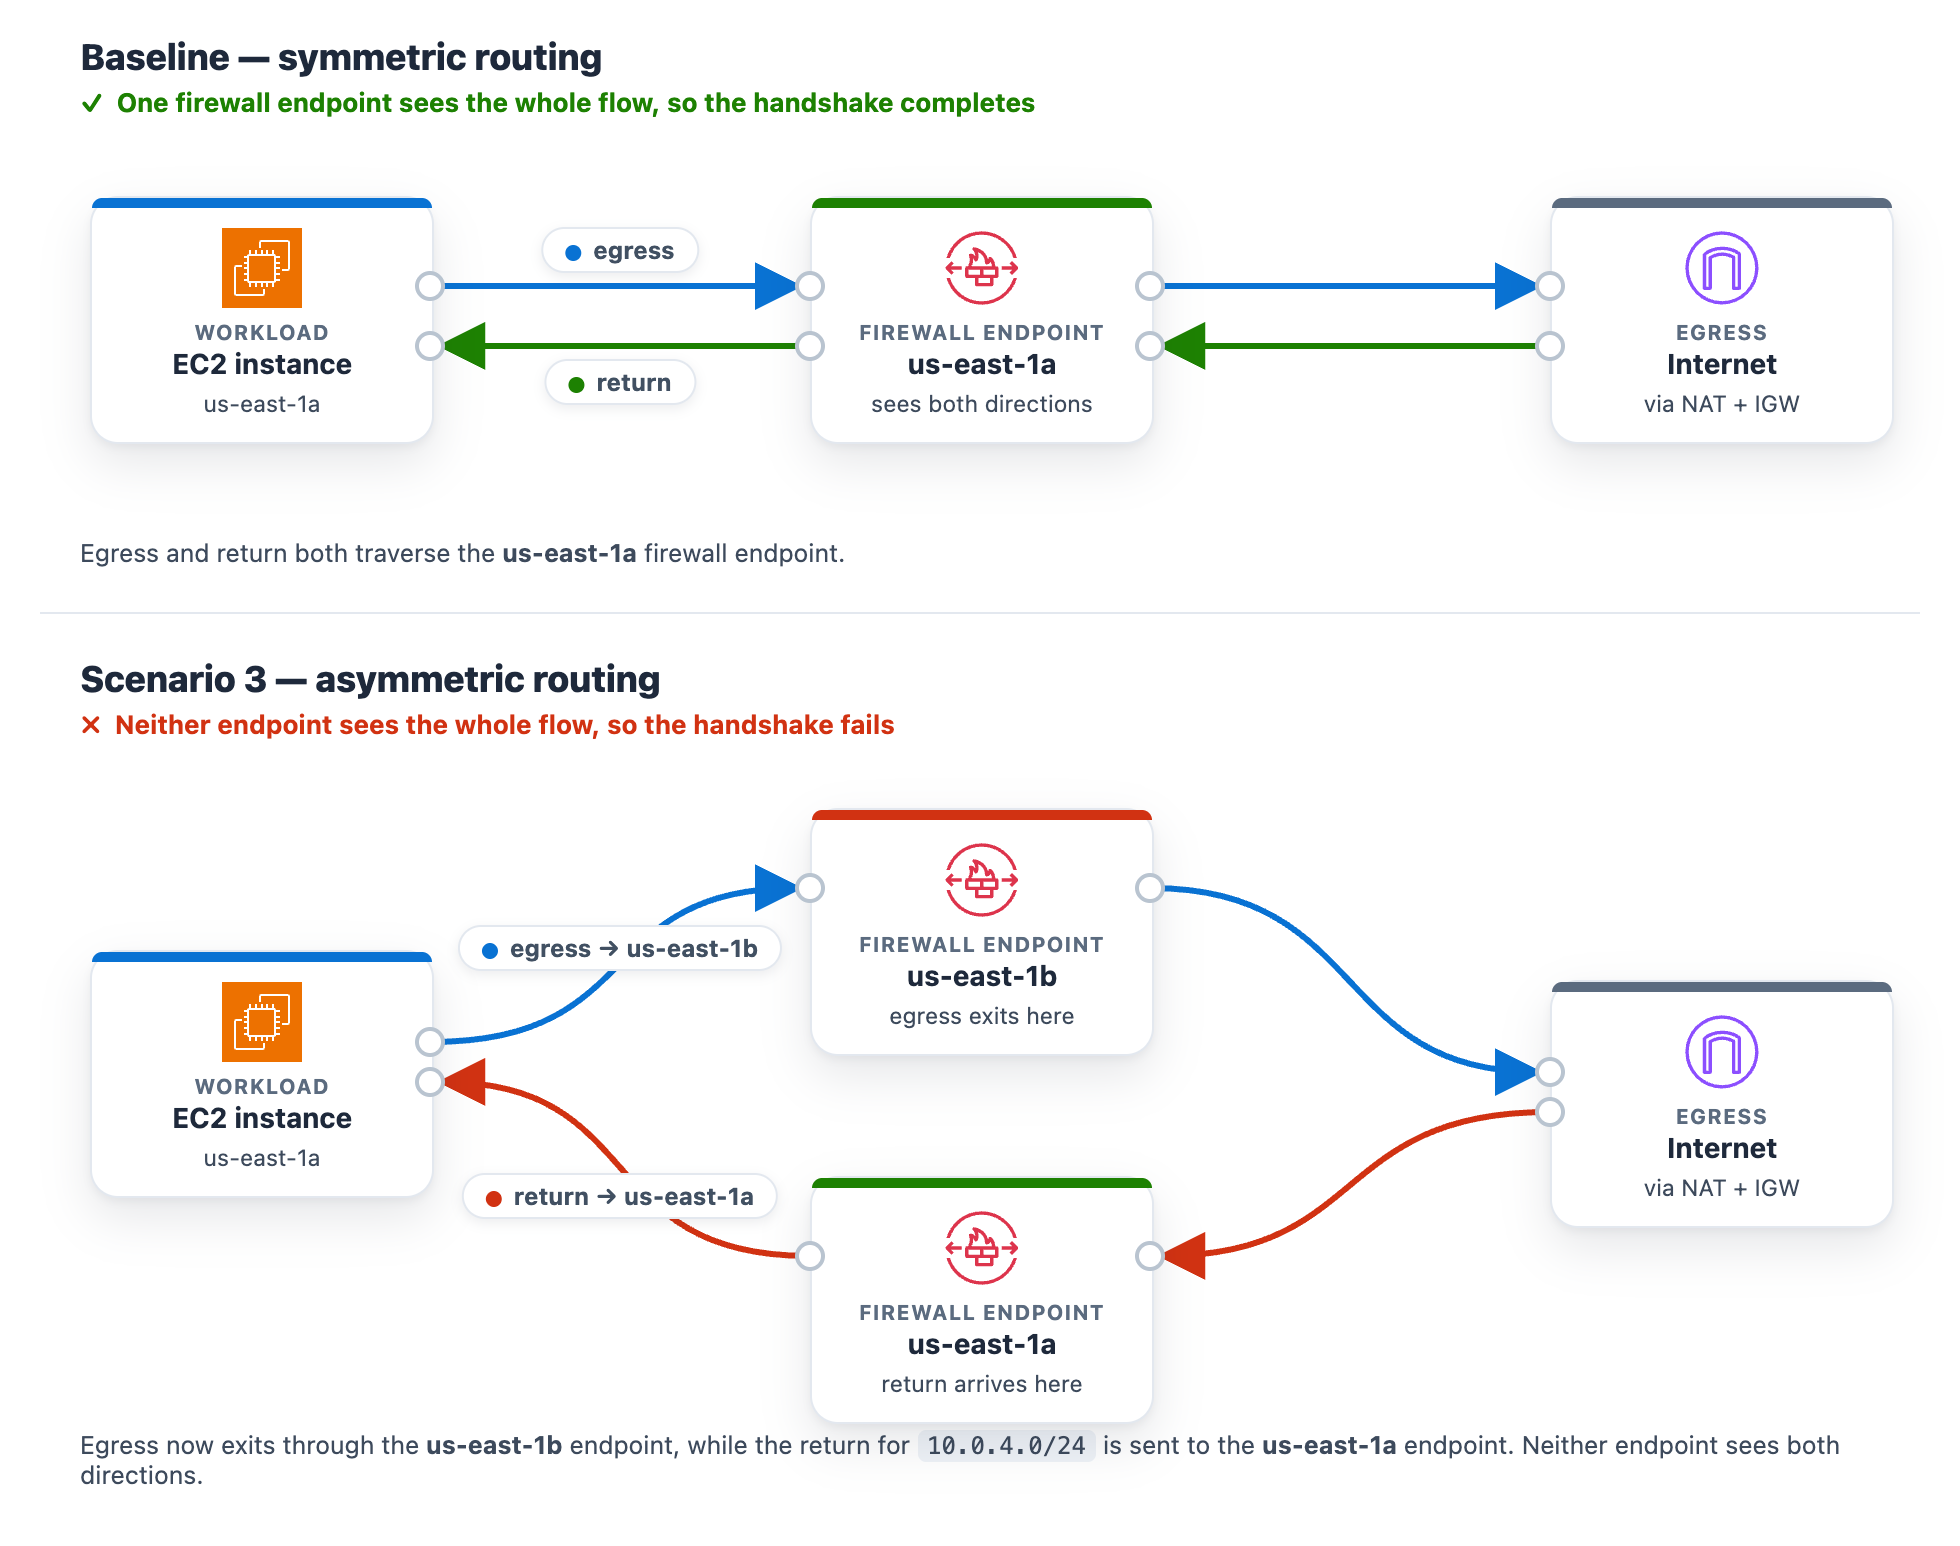
At baseline, the protected subnet in each Availability Zone routes its egress through the firewall endpoint in that same Availability Zone , and the matching return route uses that same endpoint. One endpoint sees both directions of the flow, so the stateful engine completes the handshake. The workload runs in the protected subnet in us-east-1a (CIDR 10.0.4.0/24), so at baseline its egress and its return both use the us-east-1a firewall endpoint.

Introduce the change. Make the flow asymmetric by sending egress out one Availability Zone endpoint while the return comes back through the other. This takes two route edits, and both are required. With only the first edit the flow can still complete, so the alarm will not trigger until both are saved. It makes no firewall-policy change, mirroring a real multi-Availability-Zone routing mistake.

To create asymmetric cross Availability Zone routing

  1. Go to the Amazon VPC console and choose Route tables in the navigation pane.
  2. Flip the egress. Select the NfNetworkStack/SampleVpc/protectedSubnet1 route table (the us-east-1a protected subnet, where the workload runs). On the Routes tab, choose Edit routes. Its 0.0.0.0/0 route currently targets the us-east-1a firewall endpoint. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1b firewall endpoint, then choose Save changes.
  3. Move the return. Select the NfNetworkStack/SampleVpc/publicSubnet2 route table (the us-east-1b public subnet, where egress now exits). Choose Edit routes, then Add route. For the destination enter the workload CIDR 10.0.4.0/24. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1a firewall endpoint. Choose Save changes.

After both edits, a flow’s egress leaves through the us-east-1b endpoint while its return is directed to the us-east-1a endpoint. Neither endpoint sees the whole flow.

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

What happens. A new connection leaves through one endpoint. Its return arrives at the other endpoint, which never saw the connection open, so the handshake fails. Unlike Scenarios 1 and 2, this affects the whole subnet, so all egress stops and Alarm-2 and Alarm-3 both move to ALARM. The AWS/NetworkFirewall DroppedPackets alarm (Alarm-1) stays quiet because no endpoint is making a drop decision. The flow is lost to asymmetric routing rather than counted as a firewall drop. This is why monitoring application connectivity matters. A routing fault is invisible to the firewall’s own drop counter. On the status page, the Scenario 2 card reads DROPPED (with the condition “Stateless rules dropping the monitored traffic class”) and the Scenario 3 card reads DROPPED (with the condition Return traffic dropped by asymmetric cross-Availability-Zone routing), while the Scenario 1 card stays Healthy (Figure 13). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, while the egress path from the firewall through the NAT gateway and the TLS :9142 and HTTPS · routing lines to the test endpoint turn red, which the legend defines as dropped (root cause).

Figure 13: Scenario 3 – The status page during a path-wide outage

Figure 13: Scenario 3 – The status page during a path-wide outage

Let DevOps Agent investigate. Both Alarm-2 and Alarm-3 fire in the same datapoint. DevOps Agent recognizes them as linked and merges them into a single investigation:

  1. Reads the flow logs and sees bidirectional TLS connections stop abruptly, with only one-way traffic remaining and no flows reaching the established state.
  2. Reads the firewall metrics and sees received and passed packets shift from one Availability Zone to the other at the moment of the change.
  3. Calls DescribeRouteTables and finds the egress route pointing at one Availability Zone firewall endpoint while the return route points at the other.
  4. Searches CloudTrail and surfaces the ReplaceRoute and CreateRoute calls by the same user, about a minute before both alarms fired.
  5. Reports the root cause as that asymmetric routing change. Recommends restoring symmetric same-Availability-Zone routing so egress and return traverse the same endpoint.
  6. Presents this as a plan you review and apply, not an automatic change.

A mitigation plan is a recommendation you review, not an automatic change, and the right fix depends on the intended design. Restoring symmetric routing can mean sending the workload subnet’s egress back through its own-Availability-Zone firewall endpoint (this sample’s architecture) or, in a design that doesn’t inspect this path, back through a NAT gateway. The agent infers a plausible target from what it can observe, so review the specific route it proposes against your intended topology before you apply it. (Connecting your pipeline or infrastructure-as-code, covered in the next section, lets the agent recommend the target that matches your design.)

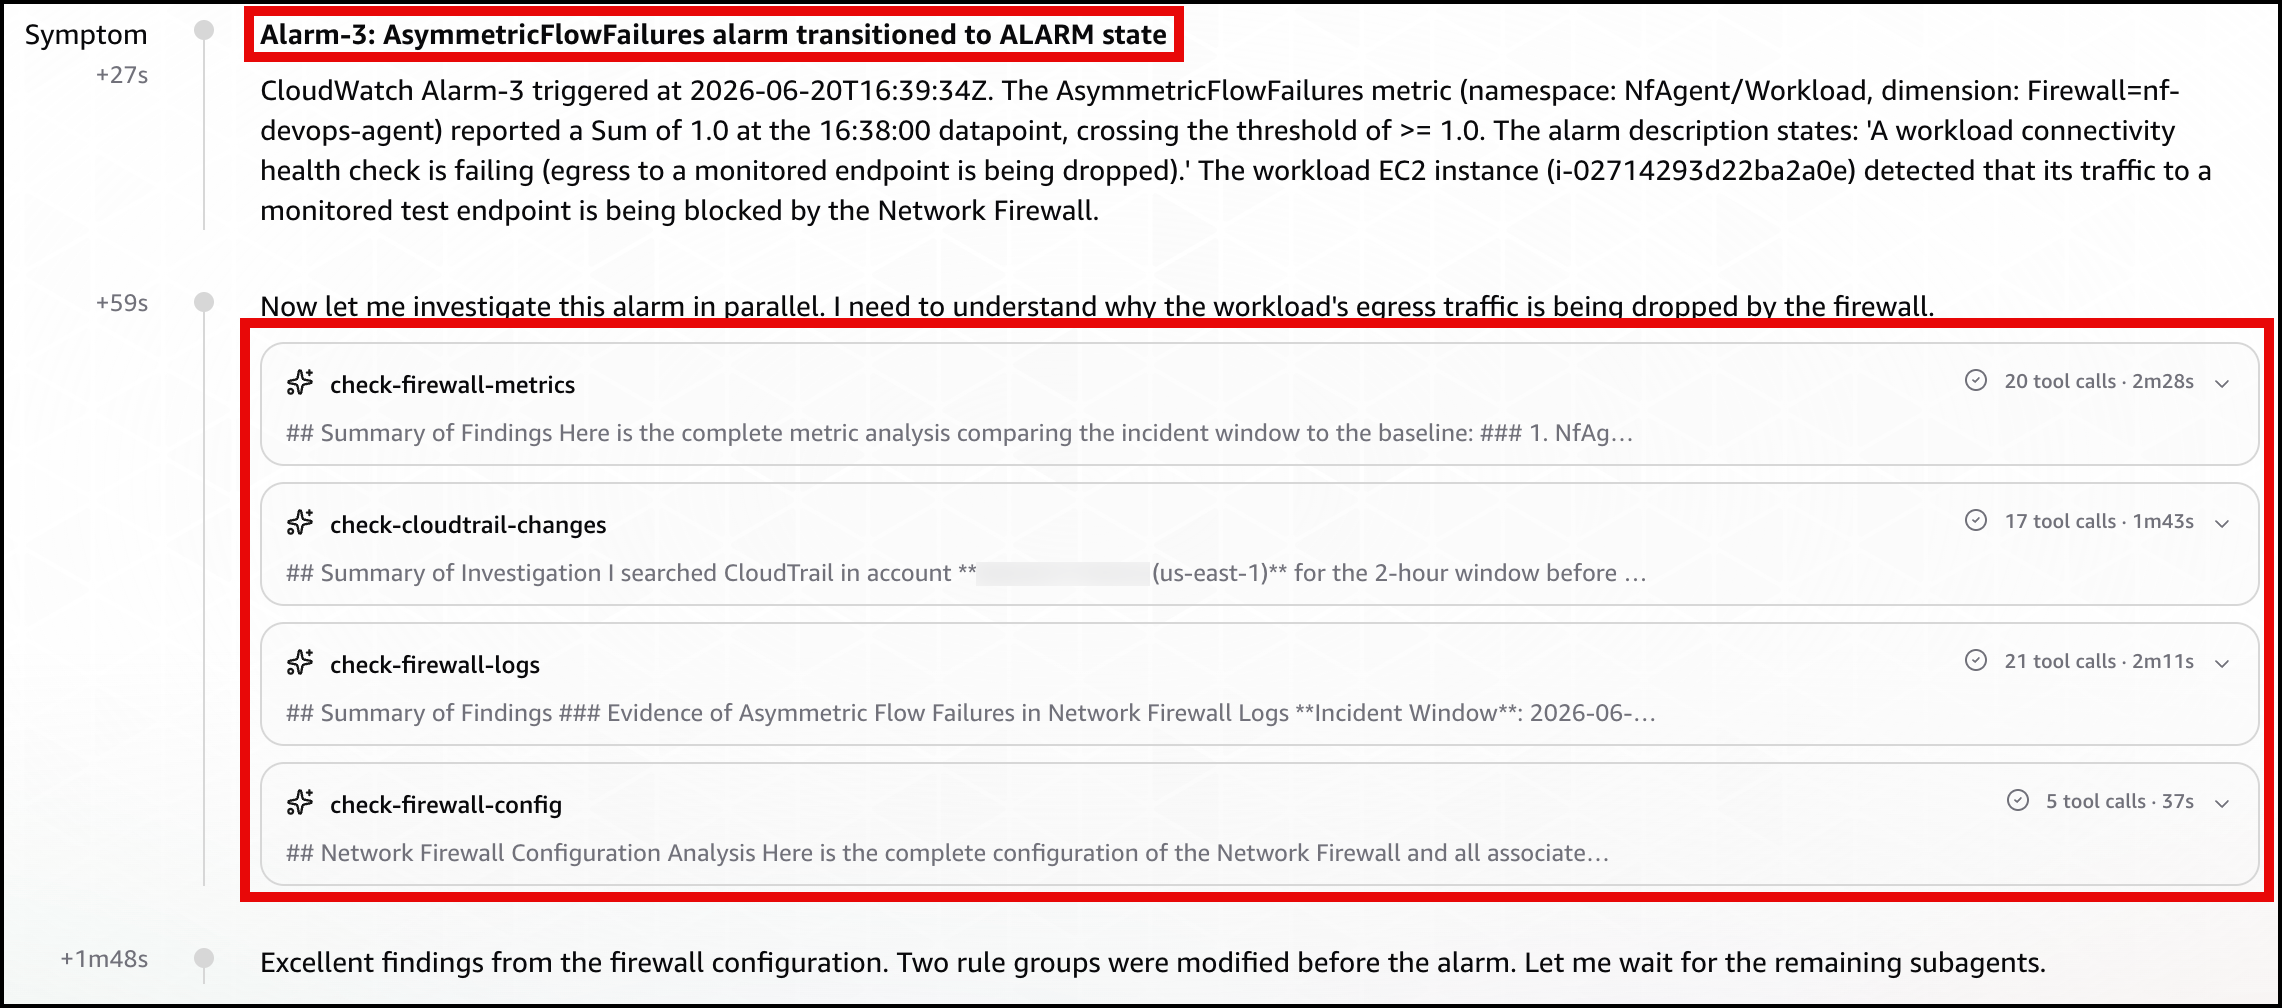
In the DevOps Agent Operator Web App view, the agent restates the Alarm-3 (AsymmetricFlowFailures) trigger and confirms the workload’s egress to a monitored endpoint is being blocked by the Network Firewall (Figure 14).

Figure 14: Scenario 3 – The symptom

Figure 14: Scenario 3 – The symptom

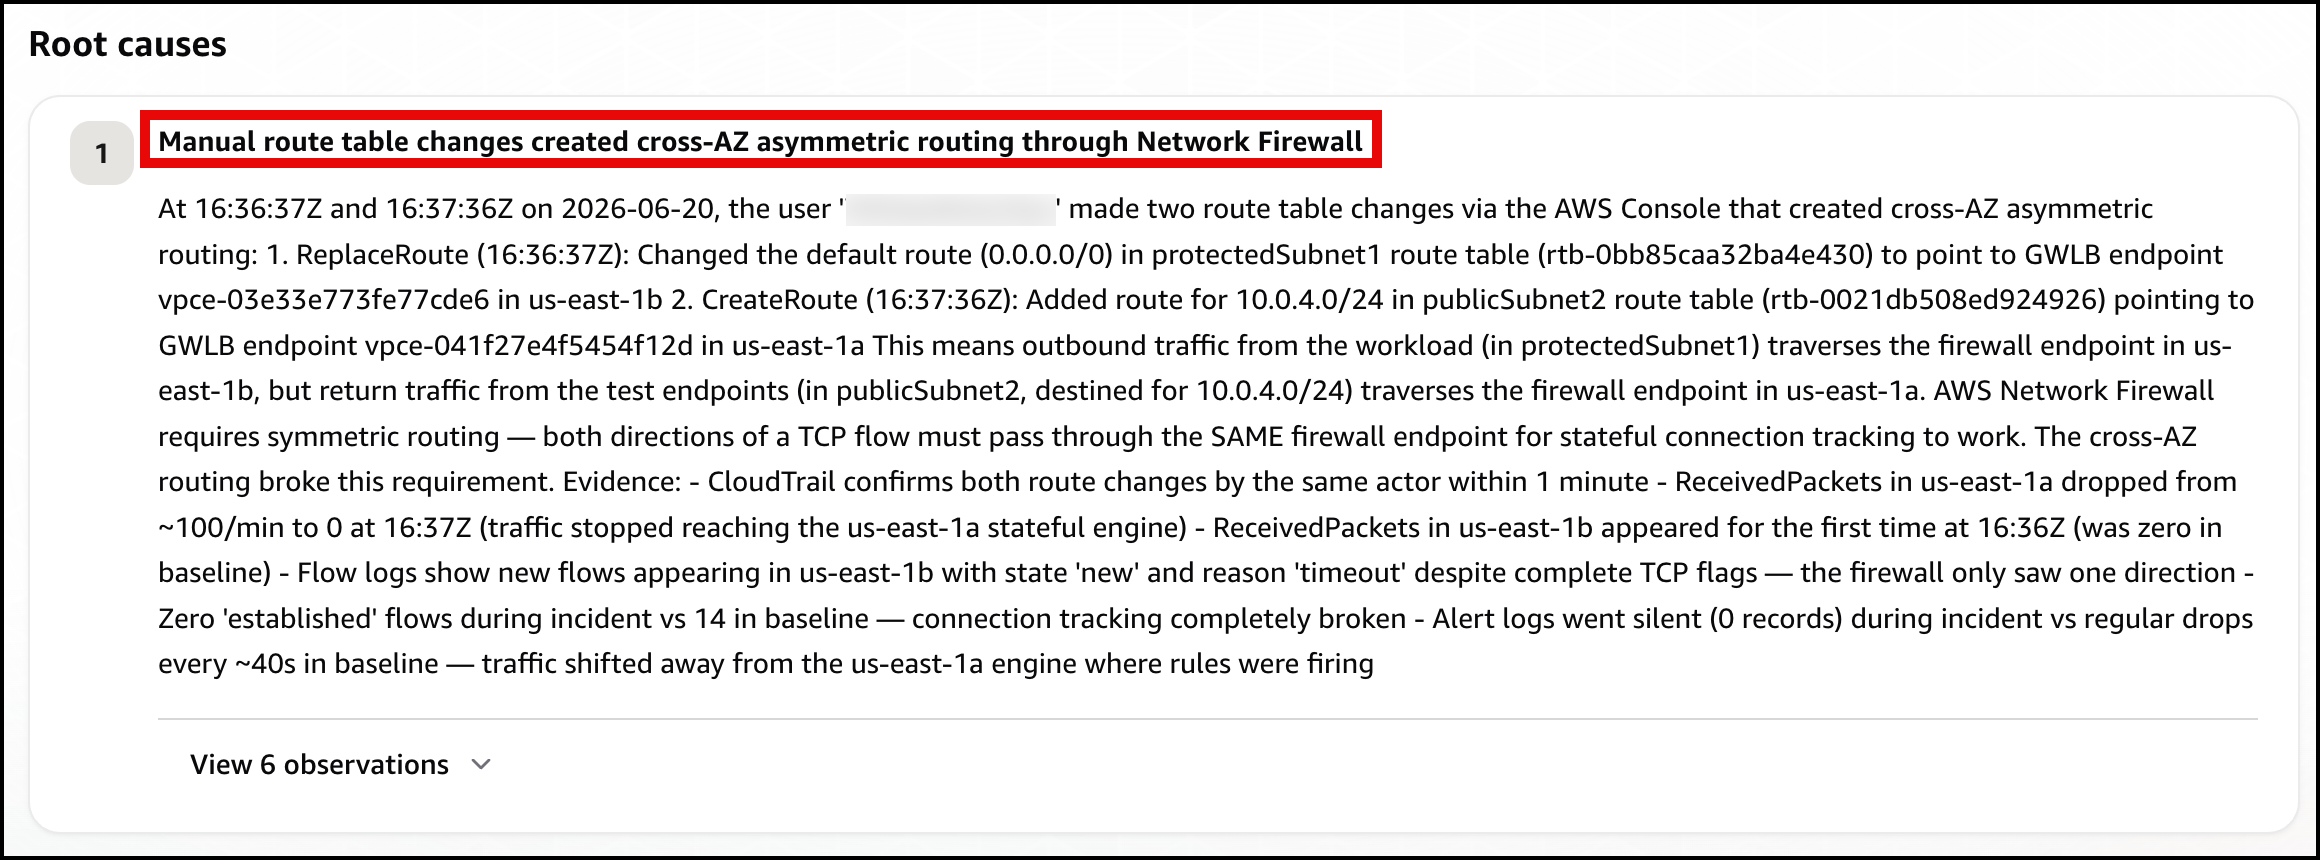
Next, the agent identifies the root cause: manual route table changes that created cross-AZ asymmetric routing through the network firewall, breaking its symmetric routing requirement (Figure 15)

Figure 15: Scenario 3 – The root cause

Figure 15: Scenario 3 – The root cause

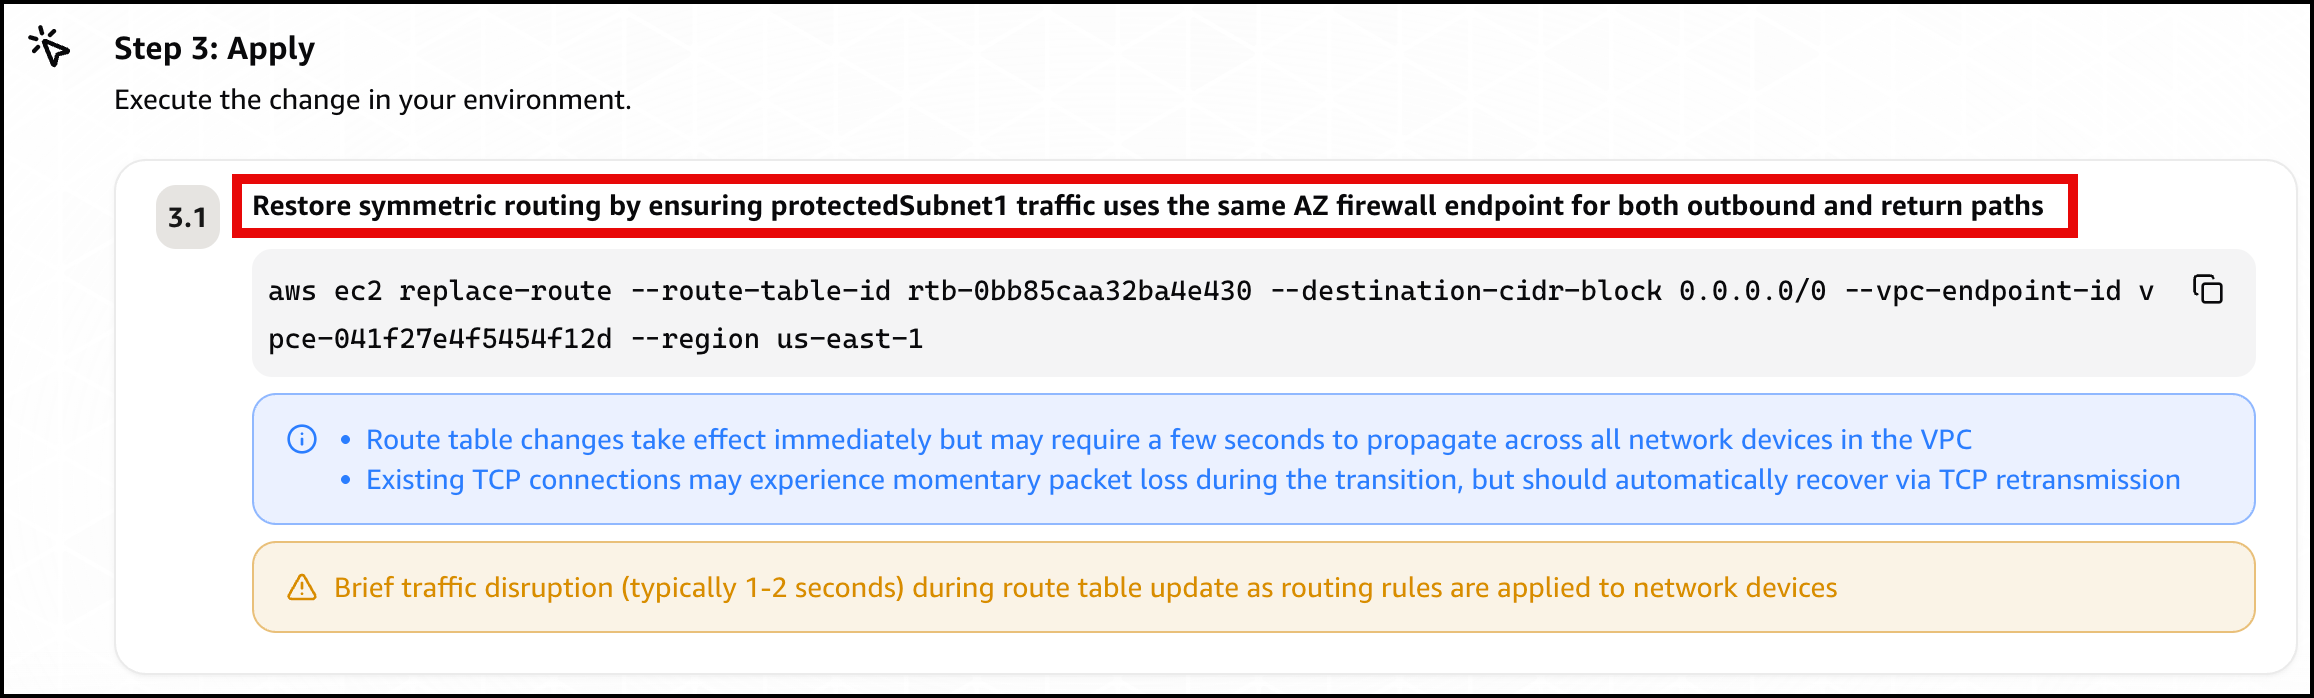
Finally, the agent presents a mitigation plan, recommending you restore symmetric routing by pointing protectedSubnet1‘s default route back to the same Availability Zone firewall endpoint, so one endpoint sees both directions of the flow again (Figure 16).

Figure 16: Scenario 3 – The mitigation plan

Figure 16: Scenario 3 – The mitigation plan

Confirm recovery. Apply the change the agent recommends, after checking the route target matches your intended design. After the workload subnet’s egress and return use the same Availability Zone firewall endpoint again, the control probe recovers, the alarms clear, and every card returns to green.

Further considerations

In production a single change can trigger several alarms at the same time, as Scenario 3 shows. DevOps Agent links related investigations and works them as one, so you review a single root cause. You can validate the linked findings or unlink an alarm to investigate it independently. If you would rather collapse alarms before they reach the agent, you can add correlation logic in the bridge Lambda function, buffering and grouping by firewall. You can also add email, Amazon Simple Queue Service (Amazon SQS), or HTTP subscribers to the SNS topic, or add the webhook Lambda function to a topic you already run. DevOps Agent produces a mitigation plan but does not change your environment on its own.

You can also give the agent more to work with. DevOps Agent connects to source repositories and CI/CD pipelines, integrating with GitHub (including GitHub Enterprise Server and GitLab Self-Managed through a private connection). It can associate AWS resources with deployments of AWS CloudFormation, AWS CDK, Amazon Elastic Container Registry (Amazon ECR) images, and Terraform. With deployed configuration and recent deployment events in view, the agent correlates the disruption against the change that introduced it and recommends a fix matching your intended design. For this sample, that means recommending the workload subnet’s own Availability Zone firewall endpoint rather than a generic symmetric path.

DevOps Agent also supports proactive incident prevention. It analyzes patterns across past investigations and delivers recommendations to prevent similar issues from recurring, including governance recommendations that strengthen deployment processes and pipeline controls. For Network Firewall rule changes, this means the agent can recommend guardrails for your CI/CD pipeline based on the classes of misconfigurations it has already resolved. You can access these recommendations through the Improvements page in the DevOps Agent Operator Web App.

Clean up

Clean up the environment with one command.

bash scripts/destroy.sh

It reverts any active scenario, runs cdk destroy for all stacks, and sweeps for stragglers by the Project = nf-devops-agent tag. The main cost drivers are the two Network Firewall endpoints, the NAT gateways (one in the main VPC for each Availability Zone, one in the test-endpoint VPC), and the test endpoint’s load balancers. Each of these bills at an hourly rate for as long as it’s provisioned, whether or not traffic is flowing, so a stack left running continues to accrue charges around the clock even while idle. Running the scenarios and tearing the stack down the same day limits the cost to a few active hours rather than days of idle hourly charges.

Conclusion

In this post, we showed you how AWS DevOps Agent accelerates troubleshooting for three common network firewall connectivity issues. The first was a domain deny list. The second was a stateless priority inversion. The third was an asymmetric cross-AZ routing drop. For each one, DevOps Agent investigated the drop and returned a root cause with a mitigation plan you approve before applying. The first scenario triggered on a prebuilt Network Firewall metric, and the other two on application health metrics. That shows both ways to alarm on a firewall problem through one pipeline.

The pattern isn’t specific to Network Firewall. The same flow fits any service that emits CloudWatch metrics and logs, such as AWS WAF, security groups, and network ACLs. Clone the sample repository to explore the solution, then apply what you learn to your own firewall, application, and alarms. For more details, see the AWS Network Firewall Developer Guide and the AWS Network Firewall pricing page. Start with the Getting Started with AWS DevOps Agent guide to connect your first webhook.

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS, specializing in helping customers design, implement, and optimize their AWS environments. He combines deep networking expertise with a passion for exploring emerging technologies to help organizations get the most out of their cloud investments. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Why and how to migrate to a Transit Gateway-attached AWS Network Firewall

Post Syndicated from Frank Phillis original https://aws.amazon.com/blogs/security/why-and-how-to-migrate-to-a-transit-gateway-attached-aws-network-firewall/

AWS Network Firewall now supports native attachment to AWS Transit Gateway. Customers commonly use Transit Gateway to route traffic from Amazon Virtual Private Cloud (Amazon VPC) networks to a centralized inspection VPC (a VPC dedicated to hosting firewall endpoints for traffic inspection) where their network firewall endpoints are deployed. This centralized deployment model reduces the need to have Network Firewall endpoints in each VPC, optimizing costs and providing a centralized point of network security control.

Customers deploying Network Firewall in a centralized deployment model using Transit Gateway have traditionally set up a dedicated inspection VPC with firewall subnets and managed the associated routing to direct traffic through the firewall. With native attachment, Network Firewall attaches directly to Transit Gateway, eliminating the need for the inspection VPC and enabling capabilities such as flexible cost allocation through Transit Gateway metering policies.

In this post, we explain what a Transit Gateway-attached network firewall is, the technical capabilities it unlocks, reasons to migrate to it, and how to perform the migration. For detailed step-by-step guidance on how to perform the migration using Terraform, AWS CloudFormation, or manually in the AWS Management Console, see the accompanying migration guide repository.

What is a Transit Gateway-attached network firewall?

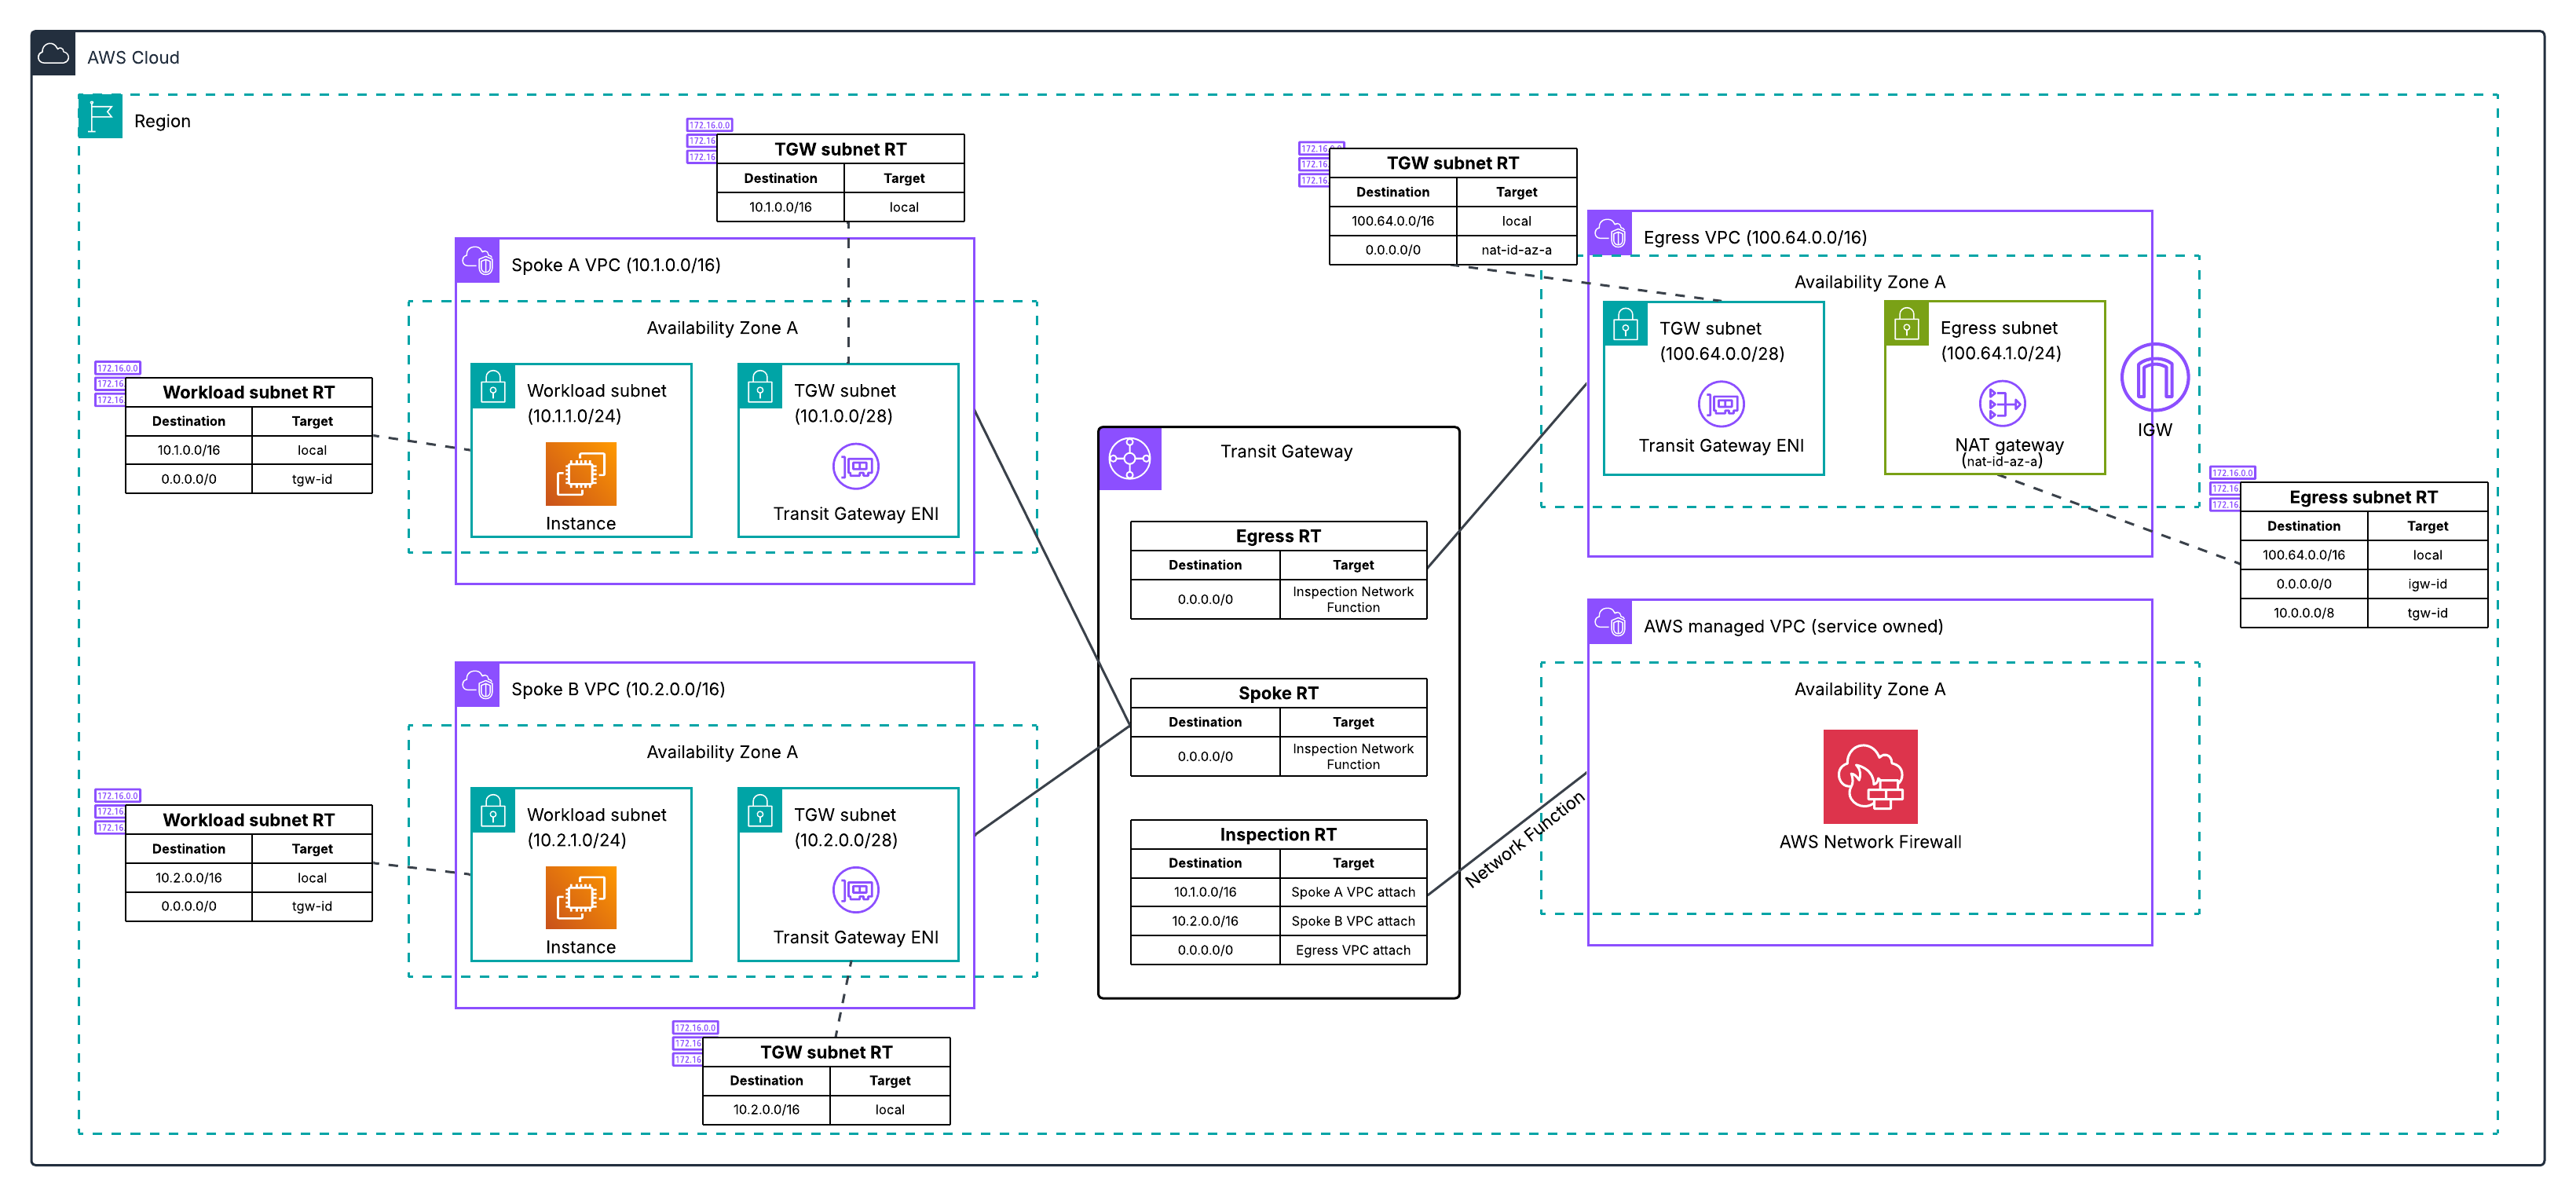
A Transit Gateway-attached network firewall simplifies your network architecture by eliminating the need for a dedicated inspection VPC. Instead of creating an inspection VPC with firewall subnets and configuring the associated routing, you create your network firewall and specify which Transit Gateway instance you want to attach it to. AWS deploys the firewall endpoints into an AWS-managed VPC on your behalf. You don’t own or manage that VPC. From your perspective, the firewall appears as a Transit Gateway network function attachment that you route traffic to, similar to other Transit Gateway attachments.

Why migrate to a Transit Gateway-attached network firewall?

You might want to migrate to a Transit Gateway-attached network firewall for the following reasons:

  • Access to flexible cost allocation: With native attachment, you can use Transit Gateway metering policies to charge back account owners for traffic they send through the centralized firewall. Flexible cost allocation for Network Firewall traffic over a Transit Gateway is only available with a Transit Gateway-attached firewall. Without native attachment, you can only allocate Transit Gateway data processing charges, not the Network Firewall charges.
  • Reduced architectural complexity: You can eliminate the inspection VPC, leaving one less VPC to manage along with its associated routing tables and subnets.

Preparing for the change

Before migrating to a Transit Gateway-attached network firewall, gather the following information and keep these key considerations in mind.

Prerequisites

When you create your new Transit Gateway-attached network firewall, you will need:

  • Transit Gateway ID: The ID of the Transit Gateway instance you will attach your network firewall to.
  • Logging configuration: Create a new logging configuration (such as new Amazon CloudWatch log groups) for the new firewall. During migration, you will be running both firewalls simultaneously. Keeping the logs separate simplifies monitoring and troubleshooting each firewall during the migration period. After migration is complete, you can point the new firewall to your existing logging destinations.
  • Firewall policy: Create a new firewall policy for the new firewall rather than reusing your existing one. During the migration period, a separate policy lets you make changes to the new firewall’s policy without affecting the existing firewall while both are running simultaneously. After migration is complete, you can attach your existing production policy to the new firewall.

Key considerations

There are some important considerations to address while planning for this change.

  • Transit Gateway encryption: Check if you’re using Transit Gateway encryption support. If encryption is enabled and required for your security posture, native attachment to Network Firewall doesn’t currently support this capability. You will need to continue using your current firewall configuration.
  • NAT gateway Elastic IPs: If you need to maintain the same public IPs (for example, for partner allowlisting), plan for this during migration. For more information, see the Preserving your NAT gateway Elastic IPs during migration section later in this post.
  • Maintenance window: Plan to perform this migration during a dedicated maintenance window. Brief network outages will occur during parts of the process, such as when swapping Transit Gateway route table associations and replacing NAT gateways.

Performing the migration

Leave your existing Network Firewall setup unchanged while setting up the new Transit Gateway-attached firewall. With this approach, you can minimize potential downtime and test the new configuration before migrating production traffic.

The migration process varies depending on your current architecture. The following sections walk through the two most common centralized Network Firewall architectures and the high-level migration process for each. For detailed step-by-step guidance on how to perform the migration using Terraform, CloudFormation, or manually in the console, see the migration guide repository.

Architecture 1: Dedicated inspection VPC with separate egress VPC

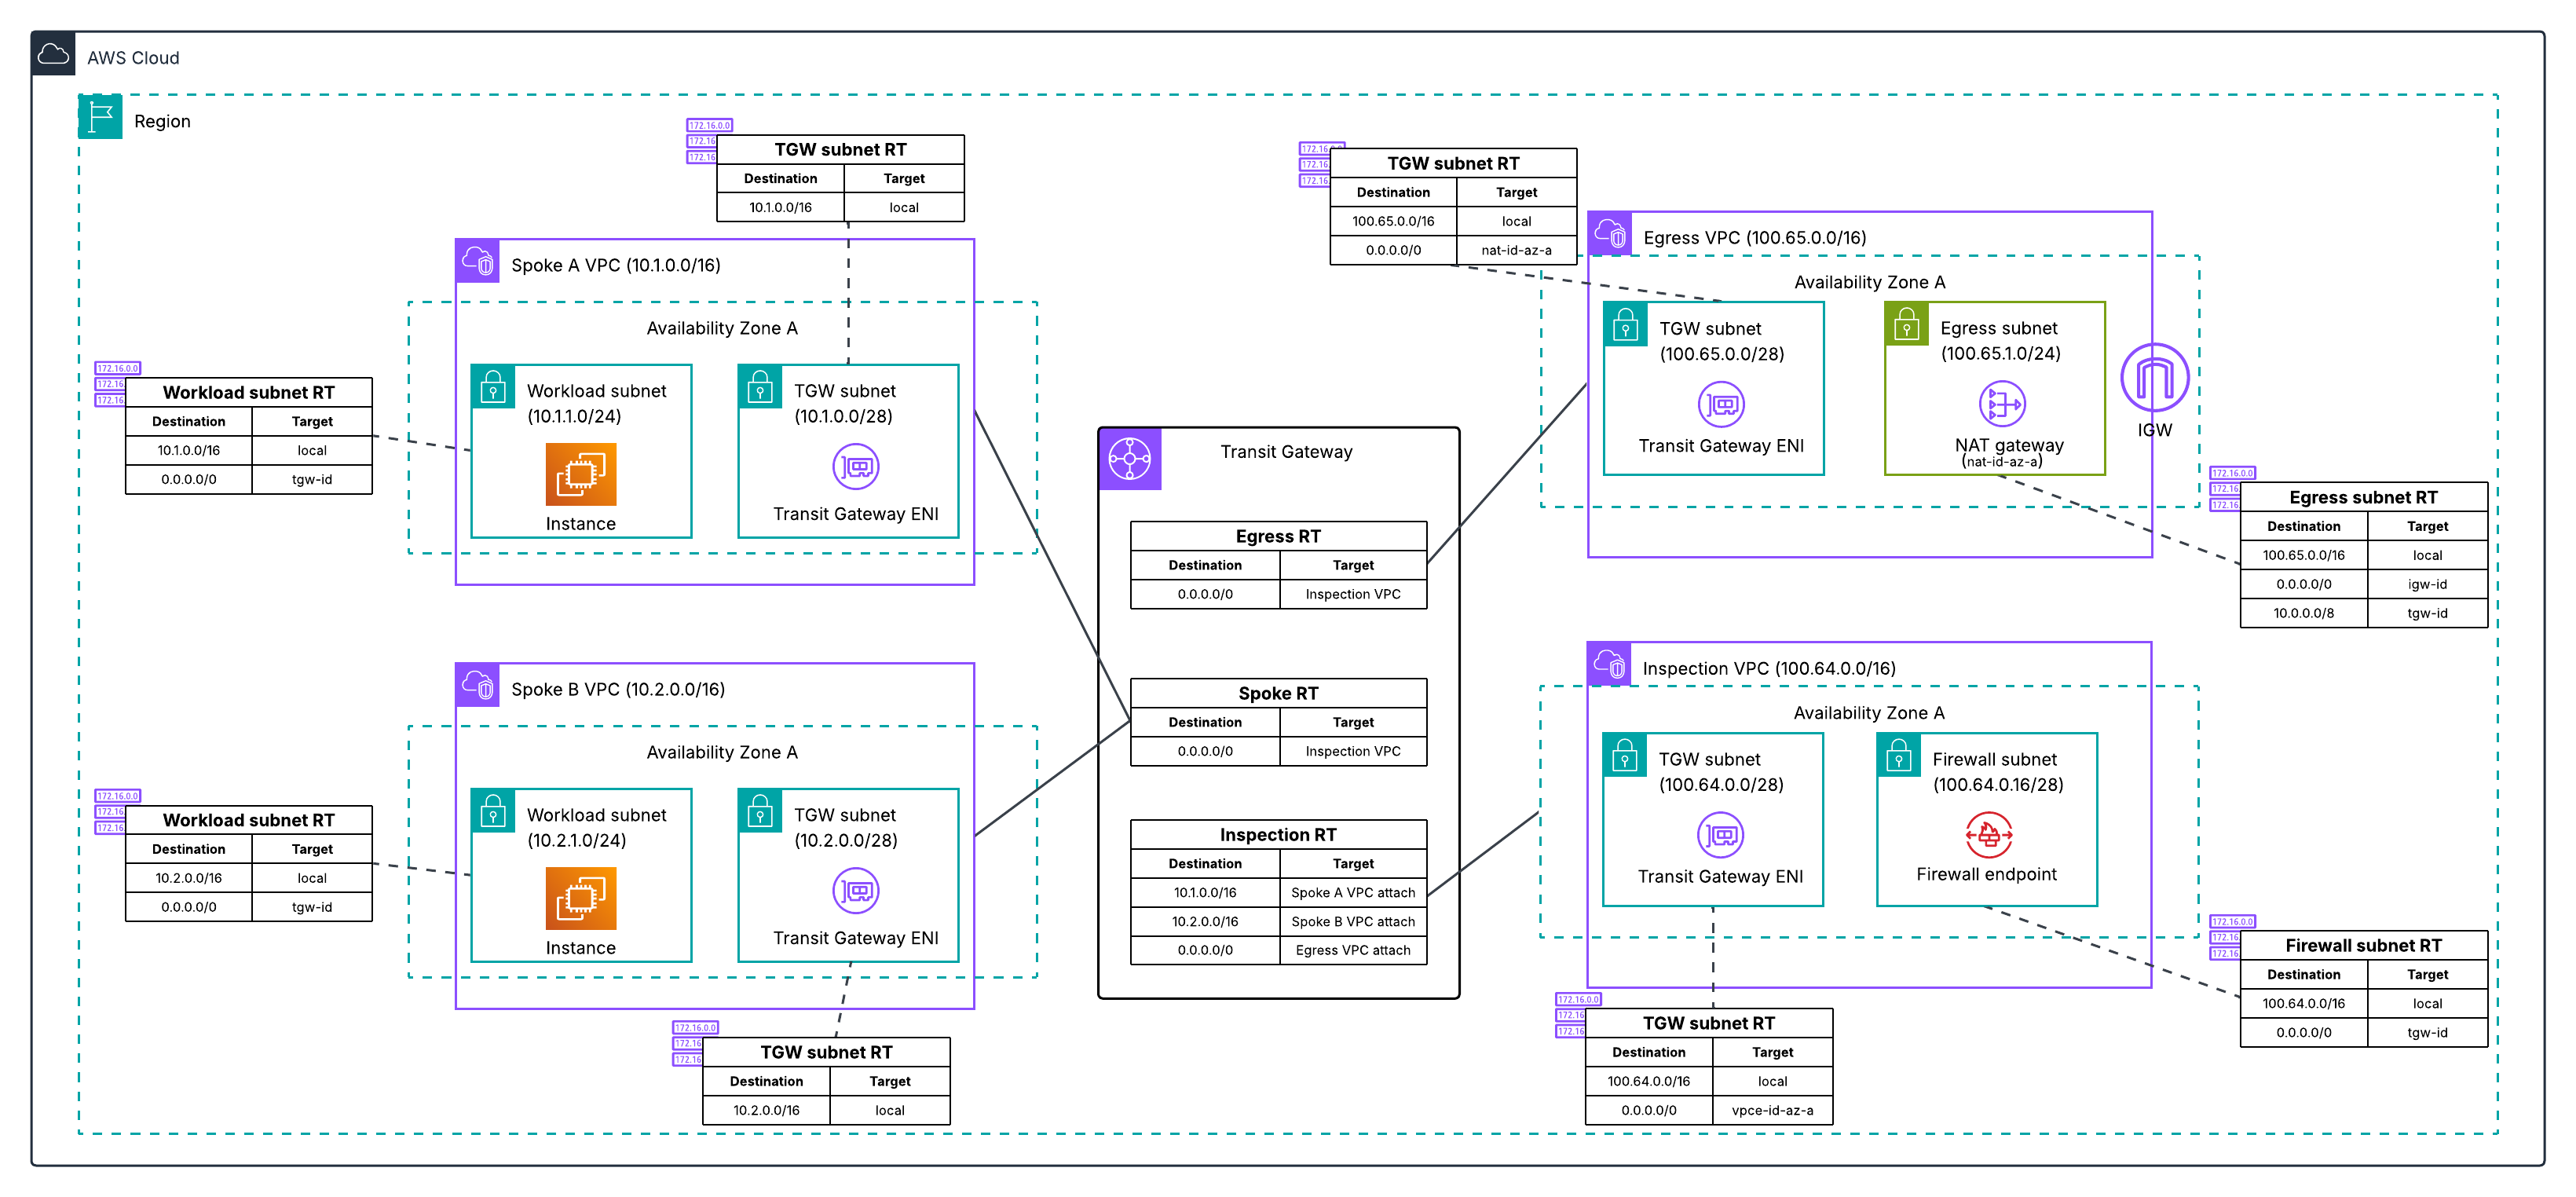
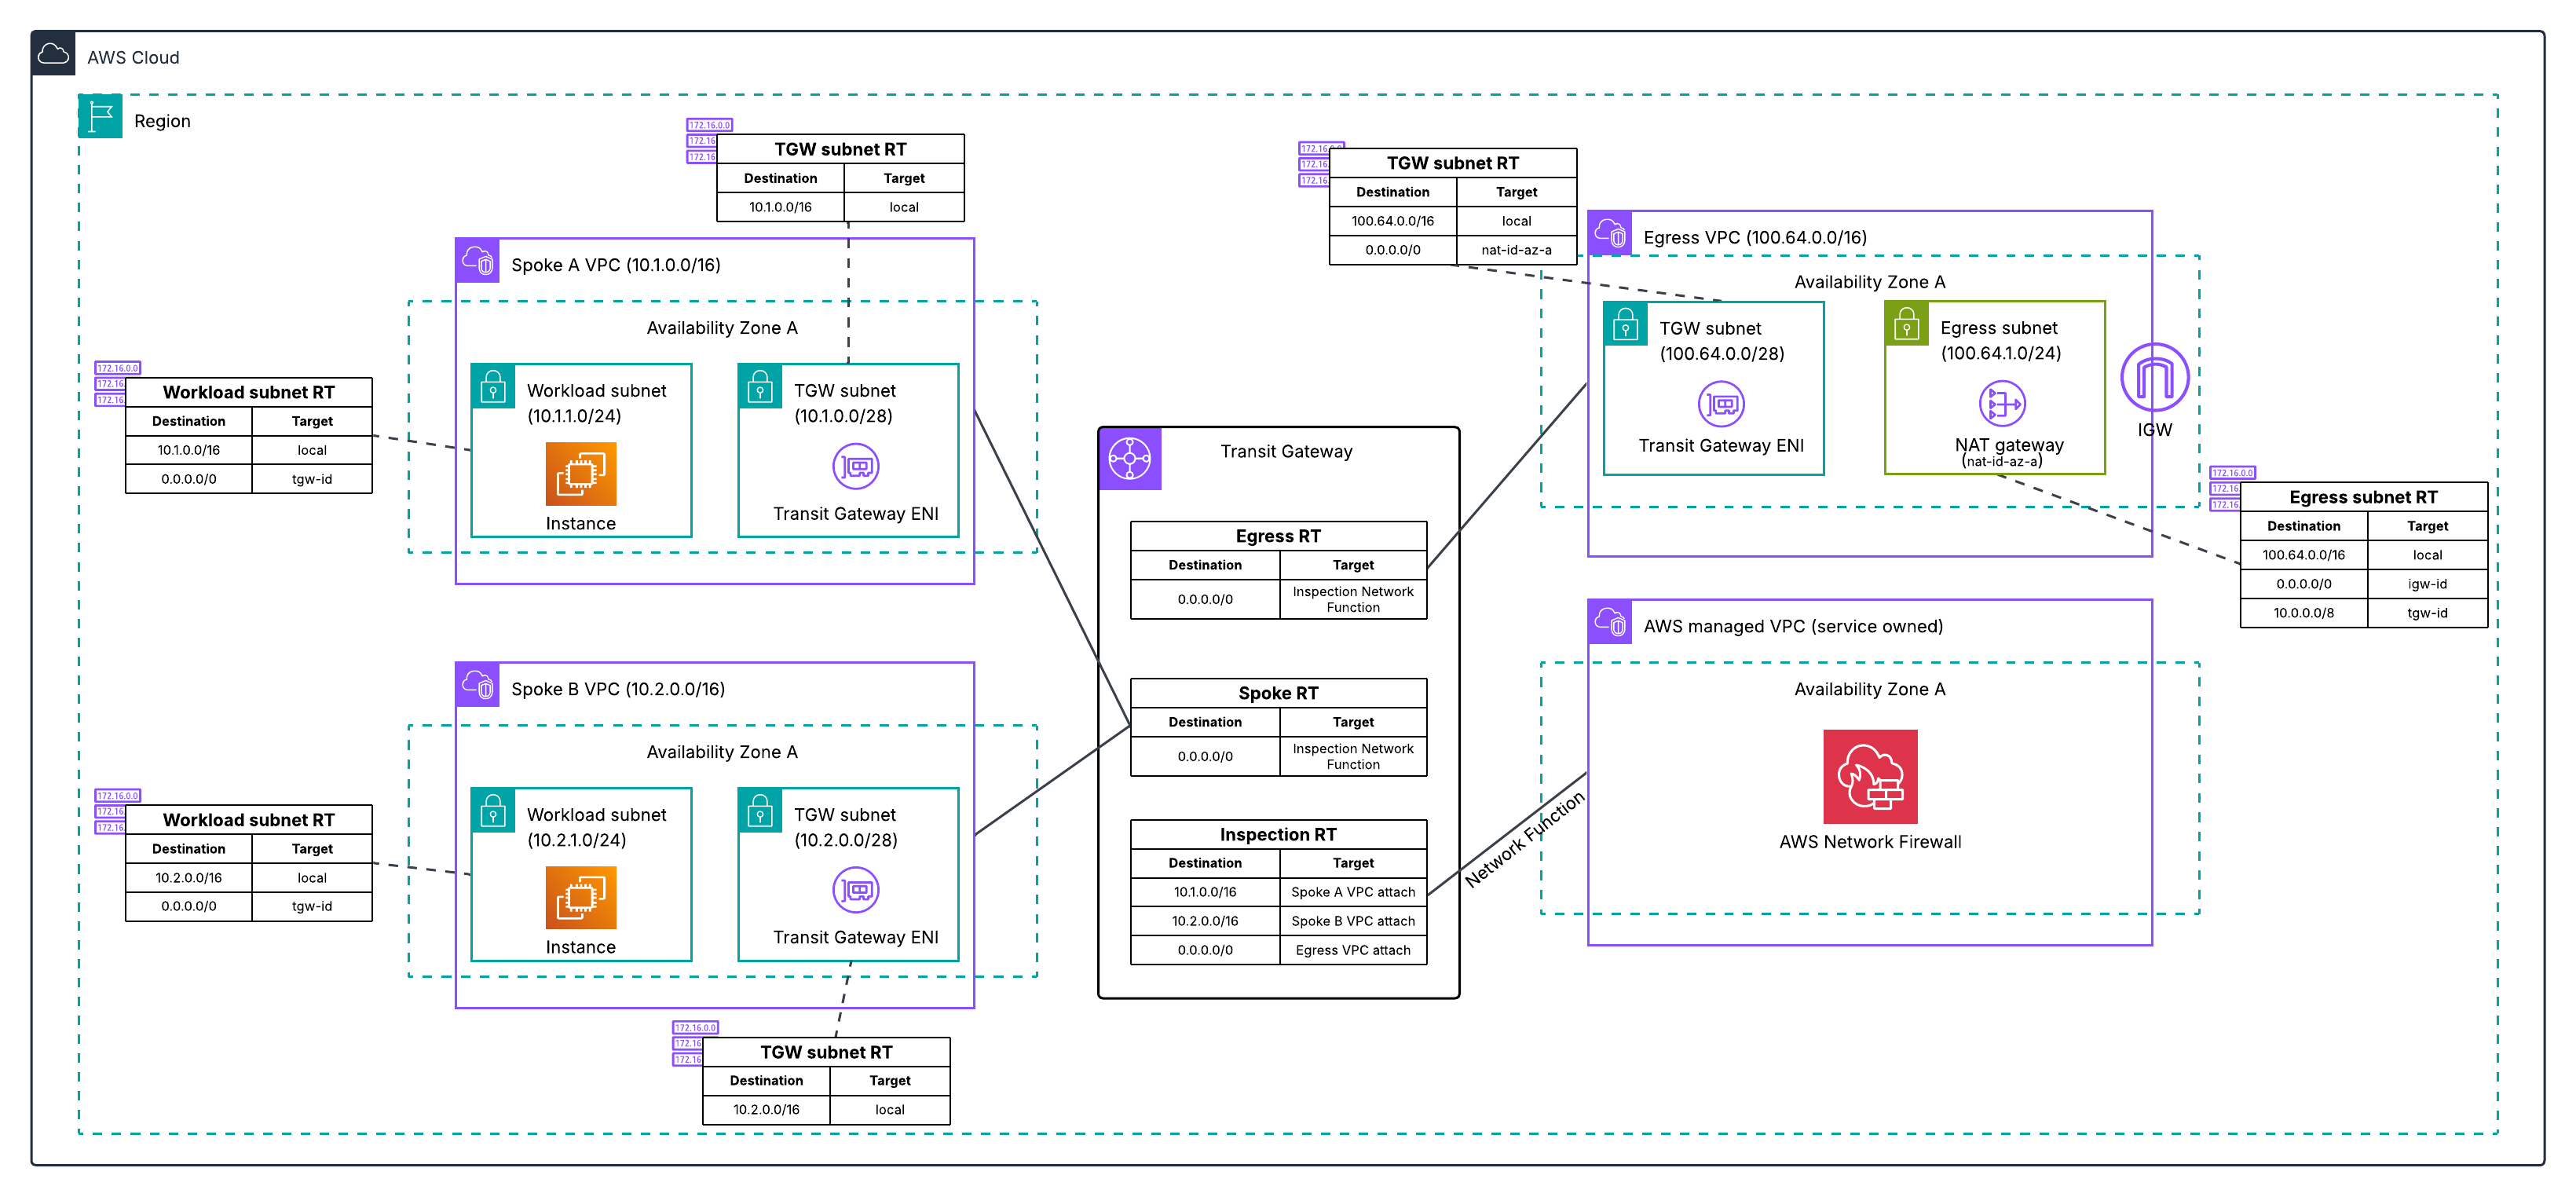
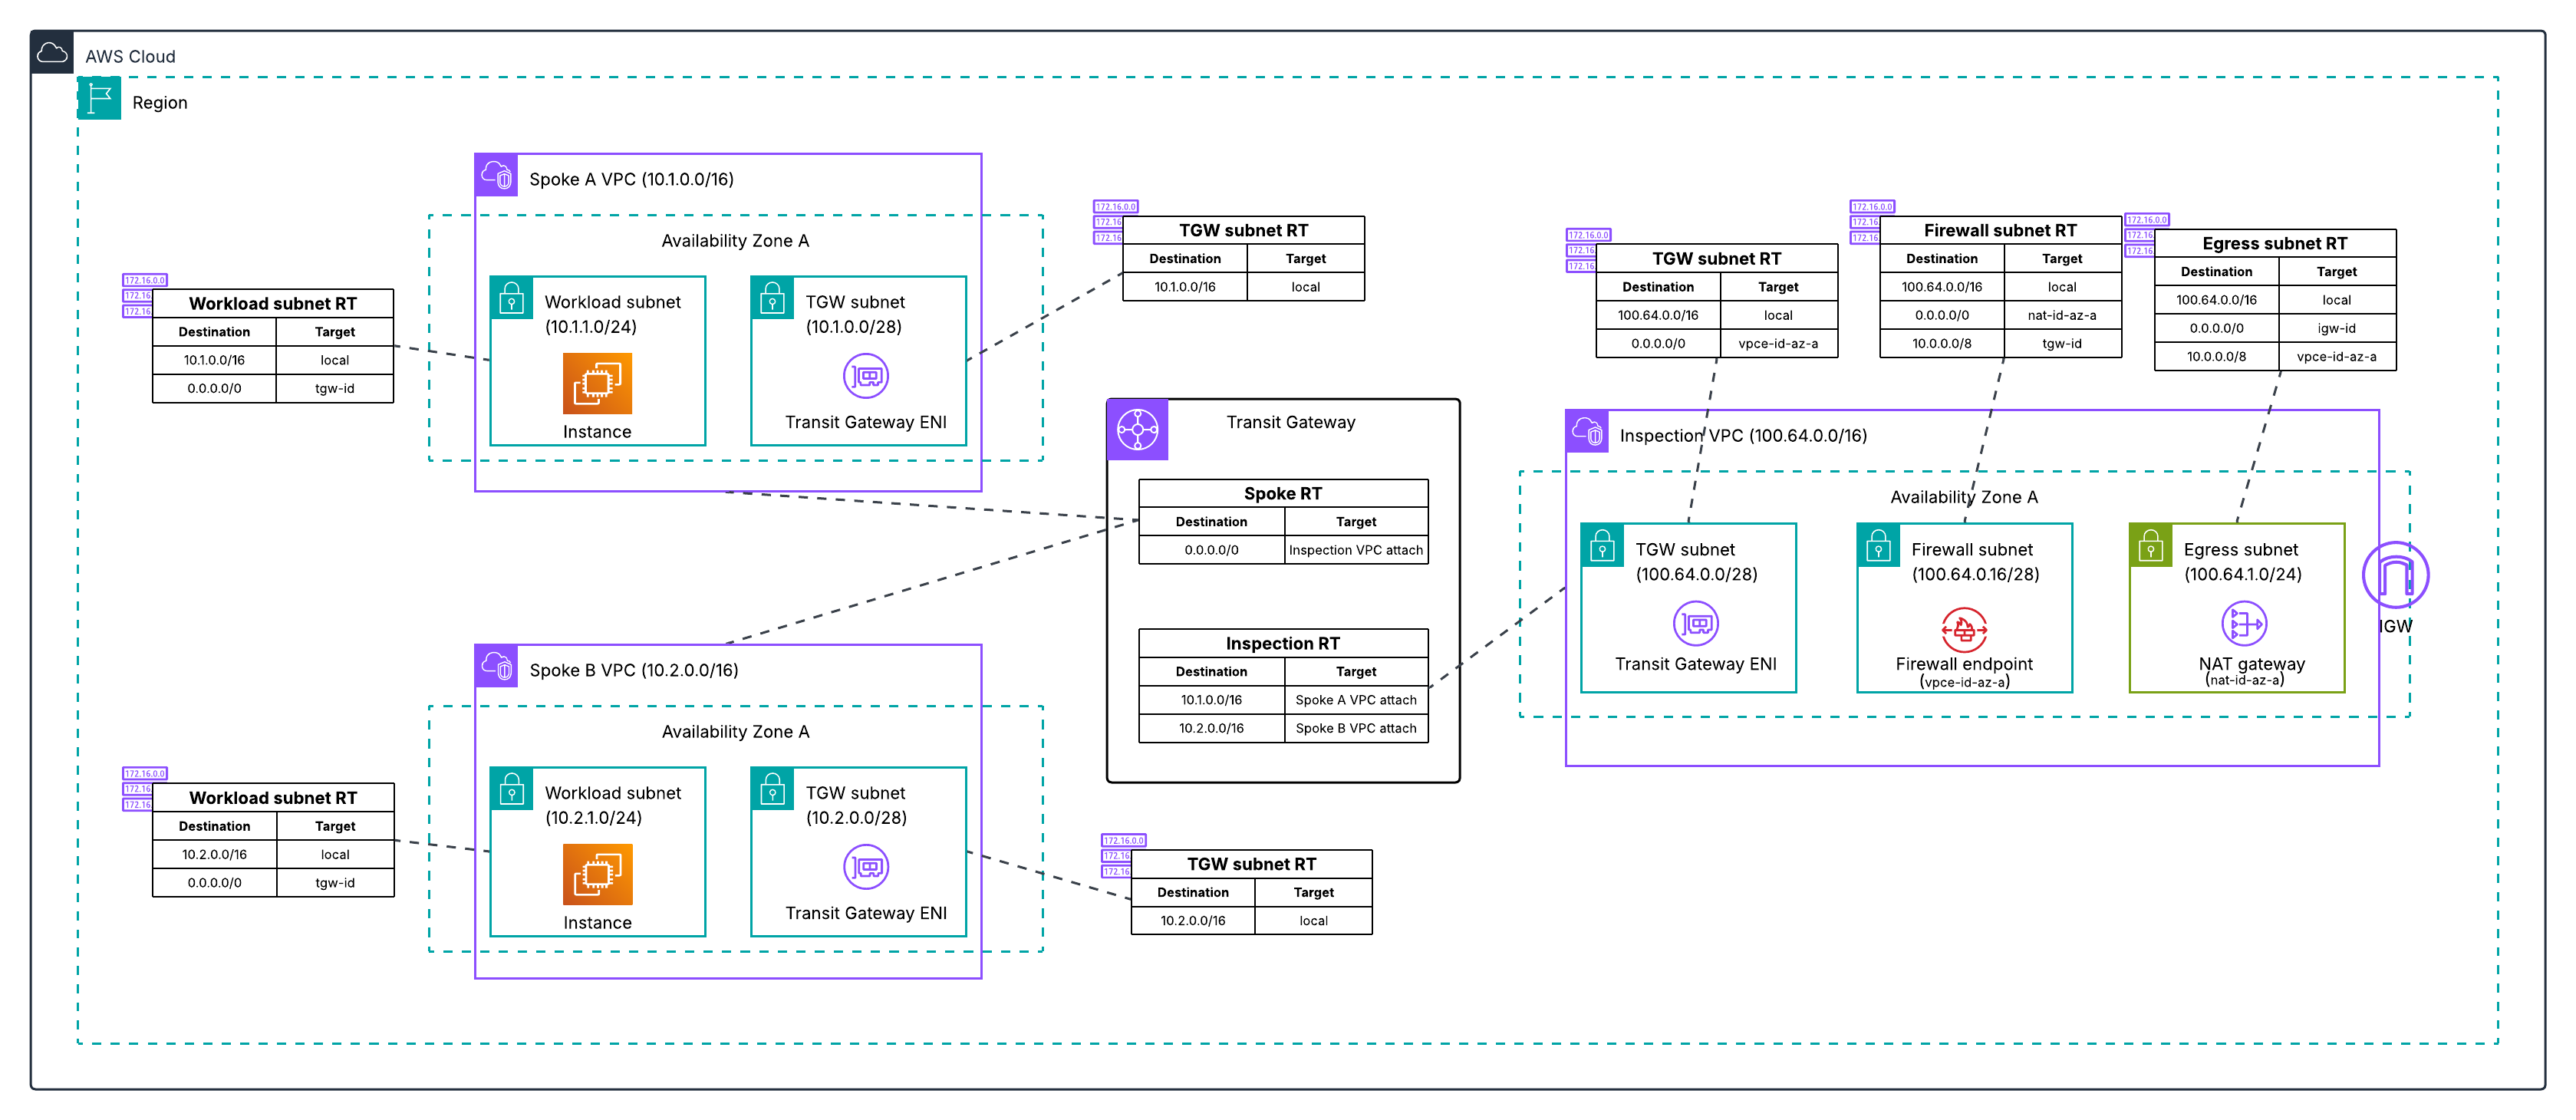
In this architecture, shown in the following diagram, you have a dedicated inspection VPC with your network firewall endpoints, and a separate dedicated egress VPC with your NAT gateways.

Figure 1: Centralized egress traffic inspection with Network Firewall and Transit Gateway, with inspection and egress separated into two VPCs.

Figure 1: Centralized egress traffic inspection with Network Firewall and Transit Gateway, with inspection and egress separated into two VPCs.

The high-level migration process for this architecture is:

  1. Deploy a new egress VPC with a temporary NAT gateway. Creating a new VPC lets you leave the existing deployment unchanged while working on the migration.
  2. Create your new network firewall with native attachment to your Transit Gateway.
  3. Configure three new Transit Gateway route tables to define the traffic path through the new firewall: an inspection route table (associated with the new firewall), an egress route table (associated with the new egress VPC), and a temporary migrated spoke route table (for testing individual spoke VPCs on the new path).
  4. Test the new firewall by moving a single spoke VPC to the new path. Verify connectivity and confirm the firewall is inspecting traffic by checking the alert logs for layer 7 (application layer) details. Layer 7 information in the alert logs indicates the firewall is seeing both directions of the traffic flow. If asymmetric routing were occurring, the firewall would only see one direction and would not be able to perform application-layer inspection, so the presence of layer 7 details confirms traffic is flowing symmetrically through the new firewall.
  5. Migrate the remaining spoke VPCs. You can migrate VPCs incrementally, or when you’re confident in the new firewall deployment, update the default route in your existing spoke route table to point to the new Network Firewall network function attachment, which moves all remaining spokes that share that route table at once.
  6. Optionally, preserve your original NAT gateway Elastic IPs by re-routing traffic back to your existing egress VPC (see Preserving your NAT gateway Elastic IPs during migration).
  7. Decommission old resources after you’ve verified that traffic is flowing correctly. Which VPCs you remove depends on whether you preserved your original EIPs (see Preserving your NAT gateway Elastic IPs during migration).
Figure 2: Post-migration architecture for Architecture 1, with the inspection VPC eliminated and traffic flowing through the Transit Gateway-attached Network Firewall to a dedicated egress VPC.

Figure 2: Post-migration architecture for Architecture 1, with the inspection VPC eliminated and traffic flowing through the Transit Gateway-attached Network Firewall to a dedicated egress VPC.

For the complete walkthrough of how to perform this migration:

Architecture 2: Combined inspection and egress VPC

In this architecture, shown in the following diagram, you have a single VPC that contains both your network firewall endpoints and your NAT gateways.

Figure 3: Centralized egress traffic inspection with Network Firewall and Transit Gateway, with inspection and egress combined in one VPC.

Figure 3: Centralized egress traffic inspection with Network Firewall and Transit Gateway, with inspection and egress combined in one VPC.

The migration process for this architecture follows the same high-level steps as Architecture 1.

  1. Deploy a new dedicated egress VPC with a temporary NAT gateway. Creating a new VPC lets you leave the existing deployment unchanged while working on the migration.
  2. Create your new network firewall with native attachment to your Transit Gateway.
  3. Configure three new Transit Gateway route tables to define the traffic path through the new firewall: an inspection route table, an egress route table, and a temporary migrated spoke route table.
  4. Test the new firewall by moving a single spoke VPC to the new path. Verify connectivity and confirm the firewall is inspecting traffic by checking the alert logs for layer 7 (application layer) details. Layer 7 information in the alert logs indicates the firewall is seeing both directions of the traffic flow. If asymmetric routing were occurring, the firewall would only see one direction and would not be able to perform application-layer inspection, so the presence of layer 7 details confirms traffic is flowing symmetrically through the new firewall.
  5. Migrate the remaining spoke VPCs. You can migrate VPCs incrementally, or once you are confident in the new firewall deployment, update the default route in your existing spoke route table to point to the new Network Firewall network function attachment, which moves all remaining spokes that share that route table at once.
  6. Optionally, preserve your original NAT gateway Elastic IPs by transferring them to the new egress VPC.
  7. Decommission the old combined VPC after you’ve verified that traffic is flowing correctly.
Figure 4: Post-migration architecture for Architecture 2, with the combined VPC eliminated and traffic flowing through the Transit Gateway-attached Network Firewall to a dedicated egress VPC.

Figure 4: Post-migration architecture for Architecture 2, with the combined VPC eliminated and traffic flowing through the Transit Gateway-attached Network Firewall to a dedicated egress VPC.

For the complete walkthrough of how to perform this migration, see:

Differences between the two migrations

Both architectures deploy the same new resources and use the same phased cutover approach. The differences are in the starting Transit Gateway routing structure (Architecture 1 has three route tables across two VPCs, Architecture 2 has two route tables in one VPC) and what you clean up at the end (two old VPCs instead of one). Both architectures converge to the same end state. For a detailed comparison, see the migration guide repository.

Minimizing downtime and testing your migration

Regardless of which architecture you’re migrating from, follow these best practices to minimize risk.

The migration guide repository includes starting architecture CloudFormation and Terraform templates for both architectures, so you can deploy the exact starting environment in a development or test account and run through the entire migration process before touching production.

Test before you migrate. Create your new Transit Gateway-attached firewall in parallel with your existing setup. Use a test VPC to validate the new configuration. Verify that logging is working correctly and that the firewall alert logs show layer 7 traffic details, which confirms there is no asymmetric routing. Test both allowed and blocked traffic scenarios before migrating production traffic.

Migrate in phases. Start with a single, non-critical workload VPC. Update only that VPC’s routes to use the new firewall attachment. Monitor and verify application behavior and performance with the application owner before proceeding. When planning your migration order, migrate spoke VPCs that have east-west traffic between each other at the same time. During the phased migration, spokes on different firewall paths will have their east-west traffic traverse two stateful firewalls. Because each stateful firewall independently tracks connection state, traffic that enters through one firewall and returns through another appears as untracked, causing the firewalls to drop or incorrectly handle the return traffic. When you’re confident in the new firewall deployment, you can update the default route in your existing spoke route table to point to the new firewall, which moves all remaining spokes that share that route table at once. Keep your old firewall configuration active until all traffic is migrated.

Prepare a rollback plan. Document your current route table configurations before making changes. Keep your existing firewall and inspection VPC active during migration. If issues arise, revert the route table changes to restore the previous configuration. Decommission old resources after you’ve verified applications are operating as expected.

Preserving your NAT gateway Elastic IPs during migration

An important consideration during migration is maintaining your existing NAT gateway Elastic IP addresses. Many organizations have these IPs allowlisted with external partners, third-party services, or in firewall rules. Changing these IPs would require coordination with multiple stakeholders and could disrupt business operations.

During migration, you need both your old and new deployments to operate simultaneously, so you can validate the new setup without impacting production traffic. This means creating temporary NAT gateways with temporary Elastic IPs in the new egress VPC.

After you’ve confirmed the new firewall deployment is stable and production traffic has been successfully migrated, you can restore your original Elastic IPs. The process differs depending on your architecture:

  • For Architecture 1 (separate inspection and egress VPCs), your existing egress VPC and its NAT gateways are independent of the inspection VPC being decommissioned. You can keep them by re-associating the existing egress VPC’s Transit Gateway attachment with the new egress route table and updating the inspection route table to route traffic there instead of the temporary egress VPC. This is a Transit Gateway routing change that takes seconds, doesn’t require deleting or creating any NAT gateways, and doesn’t increase in complexity with the number of Availability Zones. After the re-association, you delete the temporary egress VPC.
  • For Architecture 2 (combined inspection and egress VPC), the old VPC contains both the firewall endpoints and the NAT gateways. The simplest path is to decommission it and move the Elastic IPs to the new egress VPC. To do this, you delete the old NAT gateways to free the Elastic IPs, then create new NAT gateways in the new egress VPC with the original Elastic IPs. This requires a brief maintenance window while the new NAT gateways provision and must be repeated for each Availability Zone.

For the detailed step-by-step procedure, see the EIP preservation steps in the migration guide repository.

Conclusion

In this post, we explained what a Transit Gateway-attached network firewall is and how it differs from the traditional inspection VPC model, the reasons to migrate including reduced architectural complexity and flexible cost allocation, what to prepare before starting, and the high-level migration process for the two most common centralized inspection architectures. We also covered best practices for minimizing downtime, handling east-west traffic between spokes during phased migration, and preserving your existing NAT gateway Elastic IPs.

With a Transit Gateway-attached network firewall, AWS manages the firewall endpoints and the underlying VPC on your behalf, eliminating the inspection VPC from your architecture and enabling flexible cost allocation through Transit Gateway metering policies. The phased migration approach covered in this post lets you run both firewalls in parallel, validate the new path with a single spoke VPC, and cut over the rest of your traffic when you are ready.

For detailed step-by-step guidance using Terraform, CloudFormation, or the AWS Management Console for both architectures covered in this post, see the migration guide repository. The repository includes starting architecture templates so you can practice the full migration end-to-end in a test account before migrating your production environment.

If you have feedback about this post, submit comments in the Comments section below.


Frank Phillis

Frank Phillis

Frank is a Senior Solutions Architect (Security) at AWS. He enables customers to get their security architecture right. Frank specializes in cryptography, identity, and incident response. He’s the creator of the popular AWS Incident Response playbooks and regularly speaks at security events. When not thinking about tech, Frank can be found with his family, riding bikes, or making music.

Lawton Pittenger

Lawton Pittenger

Lawton is a Worldwide Security Specialist Solutions Architect at AWS, based in New York City. He specializes in helping customers design and implement effective network security controls. At AWS, he works with customers at scale and collaborates closely with service teams to drive continuous improvement in security services based on customer needs and feedback. Outside of work, his interests include skateboarding, snowboarding, and spending time in nature.

PACIFIC enables multi-tenant, sovereign product carbon footprint exchange on the Catena-X data space using AWS

Post Syndicated from Kevin S. Ridolfi original https://aws.amazon.com/blogs/architecture/pacific-enables-multi-tenant-sovereign-product-carbon-footprint-exchange-on-the-catena-x-data-space-using-aws/

This post is cowritten by Anil Akarsu and Dr. Renè Holschuh from BASF.

BASF is a global chemical industry leader and active member of the Catena-X Automotive Network. It pioneers sustainable solutions that enable automotive organizations to track carbon emissions across complex supply chains. CircularTree transforms sustainability reporting through innovative digital solutions that systematically identify and control Scope 3 greenhouse gas (GHG) emissions across global supply networks. They establish standardized data exchange protocols through participation in forward-thinking associations including PACT, Catena-X, and ESTAINIUM. BASF and CircularTree created PACIFIC, a product powered by AWS that streamlines transparent product carbon footprint (PCF) reporting across the value chain by automating PCF data exchange, reducing manual effort, and ensuring trustworthy data sharing. Through this unique relationship, AWS helps customers integrate software, services, and processes to accelerate business transformation. This post explores how PACIFIC enables multi-tenant, sovereign PCF exchange on the Catena-X data space using Amazon Elastic Container Service (Amazon ECS) on AWS Fargate, Amazon Cognito, and AWS Identity and Access Management (IAM) to deliver measurable environmental impact and competitive advantage in a carbon-conscious marketplace.

Carbon data at scale, across company borders

Sustainability is now an operational requirement, driven by growing regulatory pressure in the European Union and increasing customer expectations for credible and auditable emissions data. For manufacturers in the automotive supply chain, this is especially challenging because emissions data does not live in one place. It is distributed across fragmented tiers of suppliers, different internal systems, and partner-to-partner handoffs that still happen through spreadsheets, emails, and one-off integrations.

At the same time, the industry is converging on shared ways to exchange data, with Catena-X setting expectations for interoperability and trust in cross-company collaboration. PACIFIC was built for this reality as a multi-tenant SaaS product that enables companies to manage and exchange PCFs while maintaining data sovereignty. Its Catena-X certification signals alignment with industry standards, and the partnership with BASF grounds the platform in real supply chain requirements.

Data security, sovereignty, and interoperability

To make PCF exchange work in the real world, PACIFIC needed to solve two problems at the same time: enable frictionless collaboration across companies, while guaranteeing that each company stays in full control of their data and credentials. The platform had to operate as a multi-tenant software as a service (SaaS) for the supply chain, serving organizations on shared infrastructure without introducing any possibility of cross-tenant access.

They had to build an interoperable solution that could communicate with other solution providers on the Catena-X data space, using Eclipse Dataspace Components (EDC) connectors as a standard mechanism for cross-company data exchange. That meant enforcing strict data sovereignty, not only for PCF records but also for sensitive Catena-X integration configuration such as EDC and Digital Twin Registry (DTR) credentials. At the exchange layer, PACIFIC needed end-to-end authorization aligned with Catena-X expectations, where PCF data is shared only after explicit agreement and policy negotiation through EDC. Finally, the solution had to be practical to run and scale, so the following had to happen:

  • Onboard new companies without spinning up separate AWS accounts per tenant
  • Integrate suppliers’ PCF systems like BASF without tight coupling to the exchange workflow
  • Keep the platform secure, auditable, and operable as usage grows

Solution overview

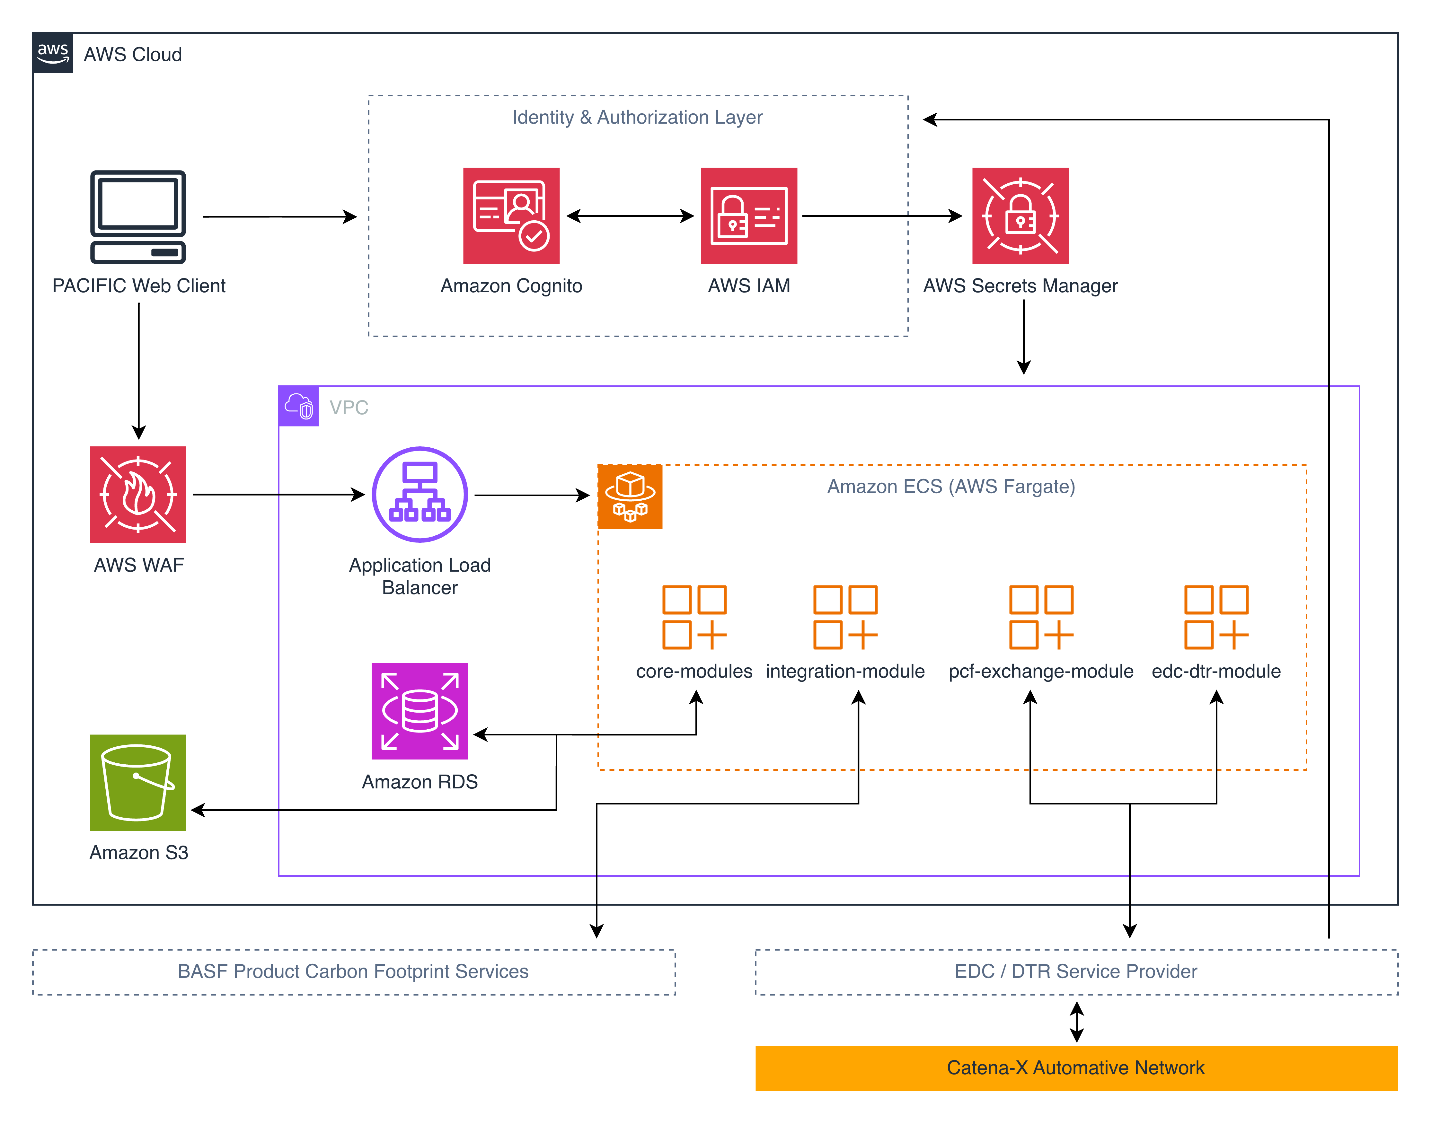
Figure 1 gives a high-level view of how PACIFIC is built and deployed to enable secure, multi-tenant PCF exchange on the Catena-X data space. It shows the main building blocks of the product, how user traffic reaches the application, how tenant-aware identity and authorization are enforced, and how PACIFIC separates core platform features from integrations and exchange endpoints. The diagram also highlights the external connections enabling interoperability, including supplier PCF data sources like BASF services, and EDC and DTR “enablement service providers” for Catena-X based data sharing.

AWS Cloud architecture diagram for the PACIFIC platform showing a multi-layered system. At the top, a PACIFIC Web Client connects to an Identity & Authorization layer containing Amazon Cognito, AWS IAM, and AWS Secrets Manager. Traffic flows through AWS WAF to an Application Load Balancer within a VPC, which distributes requests to Amazon ECS (AWS Fargate) hosting four containerized microservices: core-modules, integration-module, pcf-exchange-module, and edc-dtr-module. These modules connect to Amazon RDS for relational database storage and Amazon S3 for object storage. External integrations at the bottom include BASF Product Carbon Footprint Services, an EDC/DTR Service Provider, and the Catena-X Automotive Network. The diagram illustrates a secure, microservices-based architecture for automotive industry carbon footprint data exchange.

Figure 1: PACIFIC high-level service architecture

Data protection through IAM-based tenant isolation

A core requirement for PACIFIC is maintaining data protection and security. Each company must have exclusive control over their PCF data, EDC connector, and DTR management credentials, without any possibility of cross-tenant access. Rather than provisioning separate AWS accounts per tenant PACIFIC implements a fine-grained IAM-based isolation model built on Amazon Cognito and AWS Secrets Manager. When a company joins the platform, PACIFIC automatically provisions a dedicated IAM role with a scoped policy that permits access only to that company’s secrets in Secrets Manager. Users are assigned to an Amazon Cognito user pool group linked to their company’s IAM role. When a user authenticates, the Amazon Cognito identity pool maps their group membership to the corresponding IAM role, and AWS Security Token Service (AWS STS) issues temporary credentials for that role. This means, a user’s credentials can only retrieve their own company’s EDC secrets and access to other tenants’ configuration is denied at the IAM policy level. This architecture delivers true multi-tenant isolation using native AWS identity services, without the overhead of managing dedicated accounts or Amazon Virtual Private Cloud (Amazon VPC) per customer.

Securing PCF exchange with EDC-issued authorization tokens

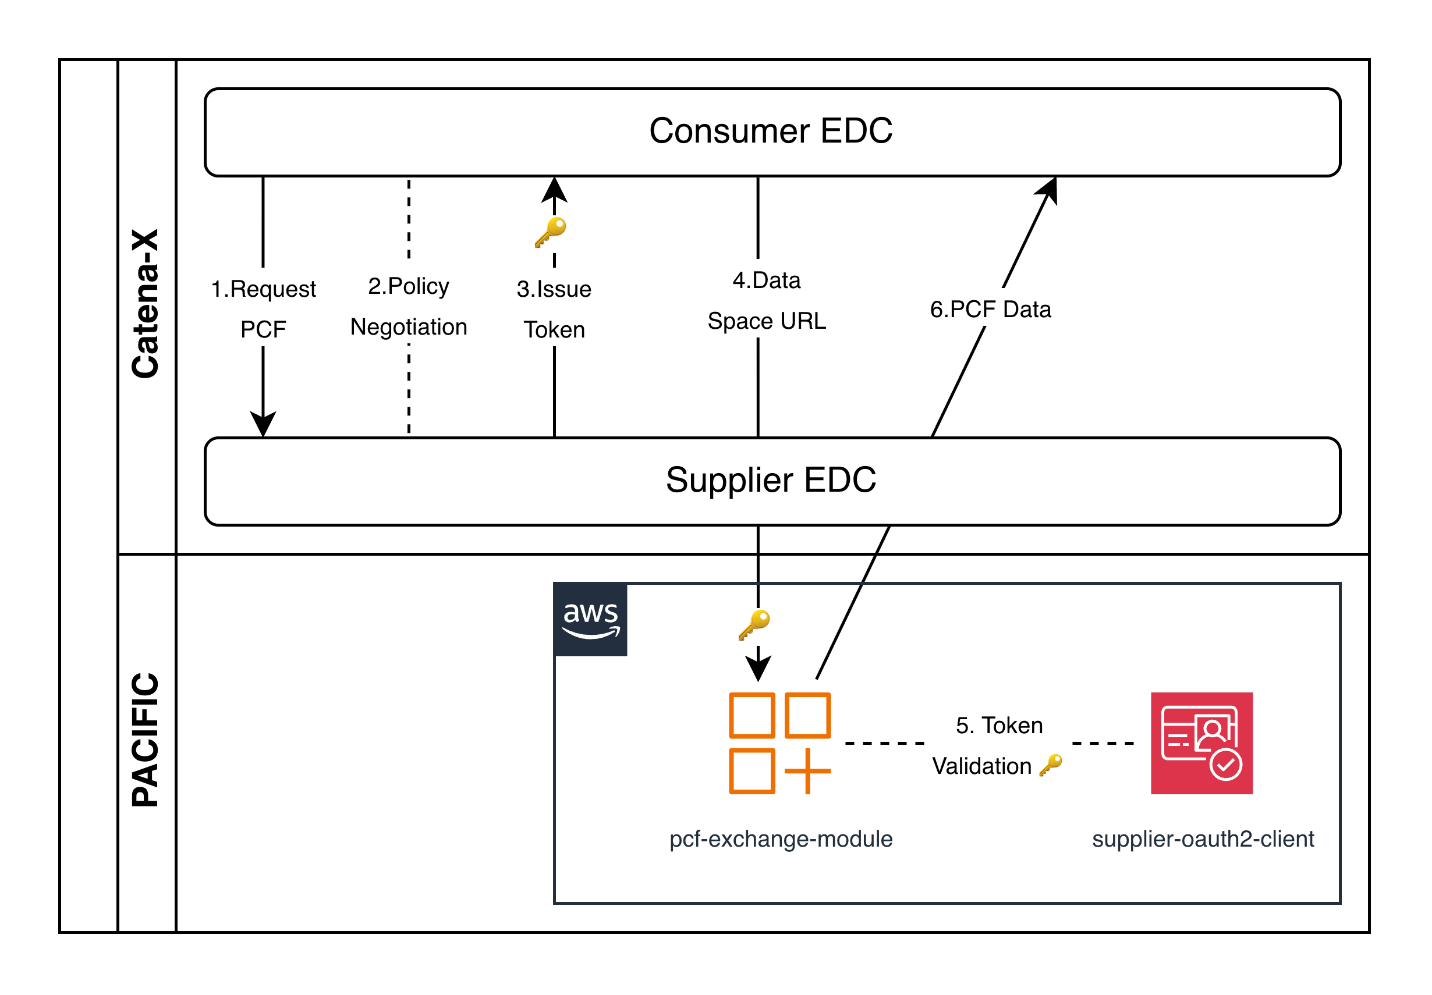
Beyond tenant isolation within PACIFIC, CircularTree enforces authorization at the data exchange layer through the pcf-exchange-module, a per-tenant endpoint that serves PCF data to authorized trading partners. When a consumer’s EDC connector requests PCF data from a supplier’s EDC, the two connectors negotiate and agree on usage policies governing how the exchanged information can be used. After this agreement is established, the supplier’s EDC issues a special authorization token to the consumer’s EDC. The token derives from the supplier company’s Cognito app client credentials stored within their EDC and grants access specifically to that supplier’s pcf-exchange-module endpoint in PACIFIC. The consumer’s EDC then uses this token to call the supplier’s dedicated endpoint and retrieve the authorized PCF data. Because each tenant’s pcf-exchange-module is published as an individual endpoint, which only accepts tokens issued through the EDC handshake process, unauthorized access is prevented at multiple levels. One level is through EDC policy negotiation, and the other is through company-scoped OAuth2 token validation. This ensures that PCF data is transmitted only after explicit consent and only to the specific trading partner authorized in the data exchange agreement. Figure 2 gives an overview of the communication flow.

Data flow diagram showing a six-step secure token exchange process between Consumer EDC and Supplier EDC systems via the PACIFIC platform on AWS. The flow proceeds as follows: (1) Consumer EDC sends a Request PCF to Supplier EDC, (2) Policy Negotiation occurs between the two EDCs (shown as a dashed line), (3) a token is issued (marked with a key icon), (4) Supplier EDC provides a Data Space URL to the pcf-exchange-module, (5) Token Validation occurs between the pcf-exchange-module and the supplier-oauth2-client component (marked with a key icon), and (6) PCF Data flows back to the Consumer EDC. The PACIFIC layer at the bottom contains two AWS-hosted components: the pcf-exchange-module (orange icon) and the supplier-oauth2-client (red icon with checkmark), demonstrating OAuth2-based secure authentication for Product Carbon Footprint data exchange.

Figure 2: EDC-to-EDC communication with Cognito Oauth2 Tokens

Integrating supplier PCF systems through the integration module

While the pcf-exchange-module handles secure data exchange between trading partners using the Catena-X data space, PACIFIC also needs to ingest PCF data from suppliers’ internal systems. Running on AWS Fargate, the integration-module provides a flexible, scalable integration layer that connects to proprietary supplier PCF systems, such as BASF’s internal PCF services. Each supplier integration requires handling unique authentication flows. This ranges from OAuth2 client credentials to certificate-based authentication or API key mechanisms, all of which are securely managed through AWS Secrets Manager. The integration-module expects incoming PCF data to already conform to the standardized Catena-X PCF JSON format, ensuring consistency at the point of ingestion. After received, PCF data is stored in Amazon Simple Storage Service (Amazon S3) under company-specific prefixes. This is where IAM policies make sure that only the PCF owner company can access their respective data. By decoupling supplier system integration from the data exchange layer, PACIFIC can onboard new supplier PCF data sources without impacting the downstream Catena-X data sharing workflows. This can be done while the S3-based storage model helps maintain strict data sovereignty, and each company’s PCF data remains isolated and accessible only to its rightful owner.

Conclusion

PACIFIC turns Catena-X PCF exchange from a specification into an interoperable, scalable workflow running on Amazon ECS and AWS Fargate without requiring companies to give up control of their data and credentials. The impact is measurable in both speed and operational scalability. From a business perspective, BASF highlights the most tangible improvement: when a requested PCF dataset is already available, a manual exchange can take up to around seven days, whereas PACIFIC responds in seconds, and can deliver automated updates when PCFs change. This capability delivers up to 75% time savings for both customers and BASF. It also reduces the time-to-data from days to seconds and making emissions information more visible and usable in day-to-day supply chain operations. PACIFIC’s multi-tenant architecture scales onboarding and operations without managing individual AWS accounts per company, while still enforcing strong tenant isolation through IAM-scoped access control and per-tenant exchange endpoints. This scalability translates into faster onboarding, enabling BASF to integrate significantly more partners into the data space. The results are measurable: an 80% increase in newly onboarded companies between 2024 and 2025, and 55% growth in requested products and shared PCFs over the same period. This provides a scalable baseline for expanding the number of onboarded organizations and increasing the volume of PCF data exchanged as adoption grows—without weakening data sovereignty or interoperability. These results underline PACIFIC’s role as a catalyst for accelerating decarbonization across supply chains.

We encourage you to join BASF, CircularTree, and AWS in industry data sharing through emerging data spaces and transparent, trusted PCF exchange across global supply networks. To explore more sustainability solutions and AWS architecture patterns, visit the AWS Architecture Blog and get started with PACIFIC through the Cofinity-X App Marketplace.


About the authors

AWS Interconnect is now generally available, with a new option to simplify last-mile connectivity

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-interconnect-is-now-generally-available-with-a-new-option-to-simplify-last-mile-connectivity/

Today, we’re announcing the general availability of AWS Interconnect – multicloud, a managed private connectivity service that connects your Amazon Virtual Private Cloud (Amazon VPC) directly to VPCs on other cloud providers. We’re also introducing AWS Interconnect – last mile, a new capability that simplifies how you establish high-speed, private connections to AWS from your branch offices, data centers, and remote locations through your existing network providers.

Large enterprises increasingly run workloads across multiple cloud providers, whether to use specialized services, meet data residency requirements, or support teams that have standardized on different providers. Connecting those environments reliably and securely has historically required significant coordination: managing VPN tunnels, working with colocation facilities, and configuring third-party network fabrics. The result is that your networking team spends time on undifferentiated heavy lifting instead of focusing on the applications that matter to your business.

AWS Interconnect is the answer to these challenges. It is a managed connectivity service that simplifies connectivity into AWS. Interconnect provides you the ability to establish private, high-speed network connections with dedicated bandwidth to and from AWS across hybrid and multicloud environments. You can configure resilient, end-to-end connectivity with ease in a few clicks through the AWS Console by selecting your location, partner, or cloud provider, preferred Region, and bandwidth requirements, removing the friction of discovering partners and the complexity of manual network configurations.

It comes with two capabilities: multicloud connectivity between AWS and other cloud providers, and last-mile connectivity between AWS and your private on-premises networks. Both capabilities are built on the same principle: a fully managed, turnkey experience that removes the infrastructure complexity from your team.

AWS Interconnect – multicloud
AWS Interconnect – multicloud gives you a private, managed Layer 3 connection between your AWS environment and other cloud providers, starting with Google Cloud, and Microsoft Azure coming later in 2026. Traffic flows entirely over the AWS global backbone and the partner cloud’s private network, so it never traverses the public internet. This means you get predictable latency, consistent throughput, and isolation from internet congestion without having to manage any physical infrastructure yourself.

Security is built in by default. Every connection uses IEEE 802.1AE MACsec encryption on the physical links between AWS routers and the partner cloud provider’s routers at the interconnection facilities. You don’t need to configure these separately. Note that each cloud provider manages encryption independently on its own backbone, so you should review the encryption documentation for your specific deployment to verify it meets your compliance requirements. Resiliency is also built in: each connection spans multiple logical links distributed across at least two physical facilities, so a single device or building failure does not interrupt your connectivity.

AWS Interconnect - multicloud - architectureFor monitoring, AWS Interconnect – multicloud integrates with Amazon CloudWatch. You get a Network Synthetic Monitor included with each connection to track round-trip latency and packet loss, and bandwidth utilization metrics to support capacity planning.

AWS has published the underlying specification on GitHub under the Apache 2.0 license, providing any cloud service provider the opportunity to collaborate with AWS Interconnect – multicloud. To become an AWS Interconnect partner, cloud providers must implement the technical specification and meet AWS operational requirements, including resiliency standards, support commitments, and service level agreements.

How it works
Provisioning a connection takes minutes. I create the connection from the AWS Direct Connect console. I start from the AWS Interconnect section and select Google Cloud as the provider. I select my source and destination regions. I specify bandwidth, and provide my Google Cloud project ID. AWS generates an activation key that I use on the Google Cloud side to complete the connection. Routes propagate automatically in both directions, and my workloads can start exchanging data shortly after.

AWS INterconnect - multicloud - provisionningFor this demo, I start with a single VPC and I connect it to a Google Cloud VPC. I use a Direct Connect Gateway. It’s the simplest path: one connection, one attachment, and my workloads on both sides can start talking to each other in minutes.

Step 1: request an interconnect in the AWS Management Console.

I navigate to AWS Direct Connect, AWS Interconnect and I select Create. I first choose the cloud provider I want to connect to. In this example, Google Cloud.

AWS interconnect - 1Then, I choose the AWS Region (eu-central-1) and the Google Cloud Region (europe-west3).

AWS interconnect - 2On step 3, I enter Description,I choose the Bandwidth, the Direct Connect gateway to attach, and the ID of my Google Cloud project.

AWS interconnect - 3

After reviewing and confirming the request, the console gives me an activation key. I will use that key to validate the request on the Google cloud side.

AWS interconnect - 4

Step 2: create the transport and VPC Peering resources on my Google Cloud Platform (GCP) account.

Now that I have the activation key, I continue the process on the GCP side. At the time of this writing, no web-based console was available. I choose to use the GCP command line (CLI) instead. I take note of the CIDR range in the GCP VPC subnet in the europe-west3 region. Then, I open a Terminal and type:

gcloud network-connectivity transports create aws-news-blog \
    --region=europe-west3  \
    --activation-key=${ACTIVATION_KEY} \
    --network=default \
    --advertised-routes=10.156.0.0/20

Create request issued for: [aws-news-blog]
...
peeringNetwork: projects/oxxxp-tp/global/networks/transport-9xxxf-vpc
...
state: PENDING_CONFIG
updateTime: '2026-03-19T09:30:51.103979219Z'

It takes a couple of minutes for the command to complete. Once the command returns, I create a peering between my GCP VPC and the new transport I just created. I can do that in the GCP console or with the gcloud command line. Because I was using the Terminal for the previous command, I continued with the command line:

gcloud compute networks peerings create aws-news-blog \
      --network=default \
      --peer-network=projects/oxxxp-tp/global/networks/transport-9xxxf-vpc \
      --import-custom-routes \
      --export-custom-routes

The network name is the name of my GCP VPC. The peer network is given in the output of the previous command.

Once completed, I can verify the peering in the GCP console.
AWS Interconnect - Peering in the Google console

In the AWS Interconnect console, I verify the status is available.

AWS Interconnect availableIn the AWS Direct Connect console, under Direct Connect gateways, I see the attachment to the new interconnect.

AWS INterconnect attachment

Step 3: associate the new gateway on the AWS side

I select Gateway associations and Associate gateway to attach the Virtual Private Gateway (VGW) that I created before starting this demo (pay attention to use a VGW in the same AWS Region as the interconnect)

AWS Interconnect associate CGW

You don’t need to configure the network routing on the GCP side. On AWS, there is a final step: add a route entry in your VPC Route tables to send all traffic to the GCP IP address range through the Virtual Gateway.

VPC Route to the VGW

Once the network setup is done. I start two compute instances, one on AWS and one on GCP.

On AWS, I verify the Security Group accepts ingress traffic on TCP:8080. I connect to the machine and I start a minimal web server:

python3 -c \
"from http.server import HTTPServer, BaseHTTPRequestHandler 
class H(BaseHTTPRequestHandler):
   def do_GET(self):
      self.send_response(200);self.end_headers()
      self.wfile.write(b'Hello AWS World!\n\n')
HTTPServer(('',8080),H).serve_forever()"

On the GCP side, I open a SSH session to the machine and I call the AWS web server by its private IP address.

AWS Interconnect : curl from GCP to AWS

Et voilà! I have a private network route between my two networks, entirely managed by the two Cloud Service Providers.

Things to know
There are a couple of configuration options that you should keep in mind:

  • When connecting networks, pay attention to the IP addresses range on both sides. The GCP and AWS VPC ranges can’t overlap. For this demo, the default range on AWS was 172.31.0.0/16and the default on GCP was 10.156.0.0/20. I was able to proceed with these default values.
  • You can configure IPV4, IPV6, or both on each side. You must select the same option on both sides.
  • The Maximum Transmission Unit (MTU) must be the same on both VPC. The default values for AWS VPCs and GCP VPCs are not. MTU is the largest packet size, in bytes, that a network interface can transmit without fragmentation. Mismatched MTU sizes between peered VPCs cause packet drops or fragmentation, leading to silent data loss, degraded throughput, and broken connections across the interconnect.
  • For more details, refer to the GCP Partner Cross Cloud Interconnect and the AWS Interconnect User Guide.

Reference architectures
When your deployment grows and you have multiple VPCs in a single region, AWS Transit Gateway gives you a centralized routing hub to connect them all through a single Interconnect attachment. You can segment traffic between environments, apply consistent routing policies, and integrate AWS Network Firewall if you need to inspect what crosses the cloud boundary.

And when you’re operating at global scale, with workloads spread across multiple AWS Regions and multiple Google Cloud environments, AWS Cloud WAN extends that same model across the world. Any region in your network can reach any Interconnect attachment globally, with centralized policy management and segment-based routing that applies consistently everywhere you operate.

My colleagues Alexandra and Santiago documented these reference architectures in their blog post: Build resilient and scalable multicloud connectivity architectures with AWS Interconnect – multicloud.

AWS Interconnect – last mile
Based on the same architecture and design as AWS Interconnect – multicloud, AWS Interconnect – last mile provides the ability to connect your on-premises or remote location to AWS through a participating network provider’s last-mile infrastructure, directly from the AWS Management Console.

The onboarding process mirrors AWS Interconnect – multicloud: you select a provider, authenticate, and specify your connection endpoints and bandwidth. AWS generates an activation key that you provide in the provider console to complete the configuration. AWS Interconnect – last mile automatically provisions four redundant connections across two physical locations, configures BGP routing, and activates MACsec encryption and Jumbo Frames by default. The result is a resilient private connection to AWS that aligns with best practices, without requiring you to manually configure networking components.

AWS Interconnect - lastmile

AWS Interconnect – last mile supports bandwidths from 1 Gbps to 100 Gbps, and you can adjust bandwidth from the console without reprovisioning. The service includes a 99.99% availability SLA up to the Direct Connect port and bundles CloudWatch Network Synthetic Monitor for connection health monitoring. Just like AWS Interconnect – multicloud, AWS Interconnect – last mile attaches to a Direct Connect Gateway, which connects to your Virtual Private Gateway, Transit Gateway, or AWS Cloud WAN deployment. For more details, refer to the AWS Interconnect User Guide.

Scott Yow, SVP Product at Lumen Technologies, wrote:

By combining AWS Interconnect – last mile with Lumen fiber network and Cloud Interconnect, we simplify the last-mile complexity that often slows cloud adoption and enable a faster, and more resilient path to AWS for customers.

Pricing and availability
AWS Interconnect – multicloud and AWS Interconnect – last mile pricing is based on a flat hourly rate for the capacity you request, billed prorata by the hour. You select the bandwidth tier that fits your workload needs.

AWS Interconnect – multicloud pricing varies by region pair: a connection between US East (N. Virginia) and Google Cloud N. Virginia is priced differently from a connection between US East (N. Virginia) and a more distant region. When you use AWS Cloud WAN, the global any-to-any routing model means traffic can traverse multiple regions, which affects the total cost of your deployment. I recommend reviewing the AWS Interconnect pricing page for the full rate card by region pair and capacity tier before sizing your connection.

AWS Interconnect – multicloud is available today in five region pairs: US East (N. Virginia) to Google Cloud N. Virginia, US West (N. California) to Google Cloud Los Angeles, US West (Oregon) to Google Cloud Oregon, Europe (London) to Google Cloud London, and Europe (Frankfurt) to Google Cloud Frankfurt. Microsoft Azure support is coming later in 2026.

AWS Interconnect – last mile is launching in US East (N. Virginia) with Lumen as the initial partner. Additional partners, including AT&T and Megaport, are in progress, and additional regions are planned.

To get started with AWS Interconnect, visit the AWS Direct Connect console and select AWS Interconnect from the navigation menu.

I’d love to hear how you’re using AWS Interconnect in your environment. Leave a comment below or reach out through the AWS re:Post community.

— seb

How to set up an air-gapped VPC for Amazon SageMaker Unified Studio

Post Syndicated from Rohit Vashishtha original https://aws.amazon.com/blogs/big-data/how-to-set-up-an-air-gapped-vpc-for-amazon-sagemaker-unified-studio/

Organizations are finding significant value using an integrated experience for all your data and AI with Amazon SageMaker Unified Studio. However, many organizations require strict network control to meet security and regulatory compliance requirements like HIPAA or FedRAMP for their data and AI initiatives, while maintaining operational efficiency.

In this post, we explore scenarios where customers need more control over their network infrastructure when building their unified data and analytics strategic layer. We’ll show how you can bring your own Amazon Virtual Private Cloud (Amazon VPC) and set up Amazon SageMaker Unified Studio for strict network control.

Solution overview

The solution covers complete technical know-how of a fully private network architecture using Amazon VPC with no public internet exposure. The approach leverages AWS PrivateLink through VPC endpoints to provide a secure communication between SageMaker Unified Studio and essential AWS services entirely over the AWS backbone network.

The architecture consists of three core components: a custom VPC named airgapped with multiple private subnets distributed across at least three Availability Zones for high availability, a comprehensive set of VPC interface and gateway endpoints for service connectivity, and the SageMaker Unified Studio domain configured to operate exclusively within this isolated environment. This design helps ensure that sensitive data never traverses the public internet while maintaining full functionality for data cataloging, query execution, and machine learning workflows.

By implementing this air-gapped configuration, organizations gain granular control over network traffic, simplified compliance auditing, and the ability to integrate SageMaker Unified Studio with existing private data sources through controlled network pathways. The solution supports both immediate operational needs and long-term scalability through careful IP address planning and modular endpoint architecture.

Prerequisites

The set up requires you to have an existing VPC (for this post, we’ll refer to the name as airgapped but in reality, it refers to the VPC you would like to securely set up SageMaker Unified Studio). If you don’t have an existing VPC, you can follow SageMaker Unified Studio domain quick create administrator guide to get started.

The high level steps to create a VPC meeting minimum requirements for SageMaker Unified Studio are as follows:

  1. In the AWS Management Console, navigate to the VPC console.
  2. Choose Create VPC.
  3. Select the VPC and more radio button.
  4. For Name tag auto-generation, enter airgapped or a name of your choice.
  5. Keep the default values for IPv4 CIDR block, IPv6 CIDR block, Tenancy, NAT gateways, VPC endpoints, and DNS options.
  6. Select 3 for Number of Availability Zones (AZs).
  7. Select 0 for Number of public subnets.
  8. Choose Create VPC.

This produces the following VPC resource map:

Figure 1 - VPC configuration

Figure 1 – VPC configuration

Set up SageMaker Unified Studio

Now, we will set up SageMaker Unified Studio in an existing VPC, named airgapped-vpc.

  1. Navigate to the SageMaker console, choose Domains in the navigation pane.
  2. Choose Create Domain.
  3. For How do you want to set up your domain?, select Quick set up.
  4. Expand the Quick set up settings
  5. Provide a name for your domain, such as airgapped-domain.
  6. For Virtual private cloud (VPC), select airgapped-vpc.
  7. For subnets, select a minimum of two private subnets.
  8. Choose Continue.
  9. Enter an email address to create a user in AWS IAM Identity Center.
  10. Choose Create domain.
  11. Once the domain is created, choose Open unified studio or use SageMaker Unified Studio URL under Domain details to access SageMaker Unified Studio.

    Figure 2 - Amazon SageMaker Unified Studio URL Welcome Page

    Figure 2 – Amazon SageMaker Unified Studio URL Welcome Page

  12. After logging in to SageMaker Unified Studio, create a project using the guided wizard.
  13. Once the project is created, we need to add the necessary VPC endpoints to allow traffic from the project to communicate to AWS services.
  14. S3 Gateway VPC endpoint was already selected as part of VPC creation step 5 in prerequisites and thus created by default. Now we must add two more VPC endpoints for Amazon DataZone and AWS Security Token Service as illustrated in following step.

These are the minimum set of VPC endpoints to allow using the tooling within SageMaker Unified Studio. For a list of other mandatory and non-mandatory VPC endpoints refer to the tables in the latter part of this post.

Create an interface endpoint

To create an interface endpoint, complete following steps:

  1. Go to the SageMaker Unified Studio Project details page and copy the Project ID.
    Figure 3 - SageMaker Unifed Studio Project Details PageFigure 3 – SageMaker Unifed Studio Project Details Page
  2. Go to the VPC console and choose Endpoints.
  3. Choose Create Endpoint.
  4. Enter a name for the endpoint, for example, DataZone endpoint for SageMaker Unified Studio.
  5. For AWS Services, enter DataZone.
    Figure 4 - Interface Endpoint creation wizard for AWS Service datazone

    Figure 4 – Interface Endpoint creation wizard for AWS Service datazone

  6. Select Service Name = com.amazonaws.us-east-1.datazone from the available options.
    Figure 5 - Interface Endpoint creation wizard network settings

    Figure 5 – Interface Endpoint creation wizard network settings

  7. Select the subnets in the airgapped-vpc that you created earlier.
  8. Filter the Security Groups by pasting the copied Project ID.
  9. Select the security group with Group Name datazone-<project-id>-dev.
  10. Choose Create Endpoint.
  11. Repeat the same steps to create a VPC endpoint for AWS STS.
  12. Once the VPC endpoints are created, validate connectivity in the SageMaker project by running a SQL query or using a Jupyterlab notebook.

For a successful domain and project which does not get into any service level usage, the mandatory VPC endpoints to be created are: S3 Gateway, DataZone, and STS interface endpoints. For other service usage dependent operations like authentication, data preview and working with compute, you would require other mandatory service specific endpoints explained later in this post.

Best practices for VPC set up for various use cases

When setting up SageMaker Unified Studio domain and project profiles, you need to specify the VPC network, subnets, and security groups. Here are some best practices around IP allocation, usage volume and expected growth to consider for different use cases within enterprises.

Production and enterprise use cases

If your organization require strict network control to meet security and compliance requirements for data and AI initiatives, consider following best practices in your production environment.

  • Use the bring-your-own (BYO) VPC approach to comply with company-specific networking and security requirements.
  • Implement private networking using VPC endpoints to keep traffic within the AWS backbone.
  • Use at least two private subnets across different Availability Zones.
  • Enable DNS hostnames and DNS Support.
  • Disable auto-assign public IP on subnets.
  • Plan IP capacity for at least 5 years. A prescriptive guidance for SageMaker Unified Studio is shared in VPC and Networking details section later in this post. Consider the following:
    • Number of users
    • Number of apps per user
    • Number of unique instance types per user
    • Average number of training instances
    • Expected growth percentage

Testing and non-production use cases

For development, testing, non-prod environment where use cases don’t have stringent security and compliance requirements, use automated setup for quick experiments. Use sample CloudFormation github templates as part of the SageMaker Unified Studio express set up, to automate domain and project creation. However, this includes an Internet Gateway which may not be suitable for security-sensitive environments.

Private networking use cases

VPCs with private subnets require essential service endpoints to allow client resources like Amazon EC2 instances to securely access AWS services. The traffic between your VPC and AWS services remains within AWS network avoiding public internet exposure.

  • Implement all mandatory VPC endpoints for core services (SageMaker, DataZone, Glue, and more).
  • Add optional endpoints based on specific service needs, like IPv4 endpoints, dual-stack endpoints, and FIPS endpoints to programmatically connect to an AWS service.
  • Work with network administrators for:
    • Preinstalling needed resources through secure channels like private subnets and self-referencing inbound rules in security groups to enable limited access.
    • Allowlisting only necessary external connections like NAT gateway IP and bastion host access in firewall rules.
    • Setting up appropriate proxy configurations if required.

External data source access use cases

Consider the following when working with external systems like third-party SaaS platforms, on-premises databases, partner APIs, legacy systems, or external vendors.

  • Consult with network administrators for appropriate connection methods.
  • Consider AWS PrivateLink integration where available.
  • Implement appropriate security measures for non-AWS data your source documents.
  • For High Availability:
    • Deploy across at least three different Availability Zones (at least two for AWS Regions with only two AZs).
    • Verify there’s a minimum of three free IPs per subnet.
    • Consider larger CIDR blocks (/16 recommended) for future scalability.

VPC and networking details

In this section, we provide details of each networking aspect starting with choice of VPCs, network connectivity details for integrated services to work, the basis of VPC and subnet requirements, and finally the VPC endpoints required for private service access.

VPC

At a high level, you have two options to supply VPCs and subnets:

  1. Bring-your-own (BYO) VPC. This is typically the case for most customers, as most have company specific networking and security requirements to reuse an existing VPC, or to create a VPC that are compliant with those requirements.
  2. Create VPC with the SageMaker quick set up template. When creating a SageMaker Unified Studio domain (DataZone V2 domain in CloudFormation) through the automated quick set up, you will be shown a Quick create stack wizard in CloudFormation which creates VPCs and subnets used to configure your domain.

    Note: The quick create stack using template URL is not intended for production use. The template creates an Internet Gateway, which is not allowed in many enterprise settings. This is only appropriate if you are either trying out SageMaker Unified Studio or, running SageMaker Unified Studio for use cases that don’t have stringent security requirements.If you choose this option, you start with SageMaker console, navigate to domains and click Create domain button, followed by Create VPC button. You will navigate to CloudFormation and click on Create stack button to create a sample VPC named SageMakerUnifiedStudio-VPC with just one-click for trying out SageMaker Unified Studio.

Figure 6 - Create VPC button in SageMaker Unified Studio Create Domain Wizard

Figure 6 – Create VPC button in SageMaker Unified Studio Create Domain Wizard

Cost estimation for recommended VPC set up

The exact cost depends on the configuration of your VPC. For more complex networking set ups (multi-VPC), you may need to use additional networking components such as a Transit Gateway, Network Firewall, and VPC Lattice. These components may incur charges, and cost depends on usage and AWS Region. Interface VPC endpoints are charged per availability zone. They also have a fixed and a variable component in the pricing structure. Use the AWS Pricing Calculator for a detailed estimate.

Network Connectivity

With regards to connectivity to the underlying AWS services integrated within SageMaker Unified Studio, there are two ways to enable connectivity (these are not Studio specific, these are standard ways to enable network connectivity within a VPC). This is an important security consideration that depends on your organization’s security policies.

  1. Through the public Internet. Your traffic will traverse over the public Internet through an Internet Gateway in your VPC.
    1. Your VPC must have an Internet Gateway attached to it.
    2. Your public subnet must have a NAT Gateway. In addition, your public subnet’s route table must have a default route (0.0.0.0 for IPv4) to the Internet Gateway. This route is what makes the subnet public.
    3. Your private subnets must have a default route to the public subnet’s NAT Gateway.
  2. Through the AWS backbone. Your traffic will remain within the private AWS backbone through PrivateLink (by provisioning Interface and Gateway endpoints for the necessary AWS services in each Availability Zone).
    1. A list of all the AWS services integrated into Studio and the VPC endpoints required can be found in section VPC Endpoints covered later in this post.
    2. For non-AWS resources, certain external providers of these services may offer PrivateLink integration. Check with each provider’s documentation and your network administrator to understand the most suitable way to connect to these external providers.

In a private networking scenario, you will need to consider whether you need connectivity to non-AWS resources in a way that’s compliant with your organization’s security policies. A few examples include the following:

  1. If you need to download software in your remote IDE host (for example, command line programs, such as Ping and Traceroute)
  2. If you have code that connects to external APIs.
  3. If you use software (such as JupyterLab or Code Editor extensions) that rely on external APIs.
  4. If you depend on software dependencies hosted in the public domain (such as Maven, PyPi, npm)
  5. If you need cross-Region access to certain resources (such as access to S3 buckets in a different Region)
  6. If you need functionality whose underlying AWS services do not have VPC endpoints in all Regions or any Region.
    1. Amazon Q (powers Q and code suggestions)
    2. SQL Workbench (powers Query Editor)
    3. IAM (powers Glue connections)

If you need to connect to data sources outside of AWS (such as Snowflake, Microsoft SQL Server, Google BigQuery)
Enterprise network administrators must also complete either of the following prerequisites to handle private networking scenarios:

  1. Preinstall needed resources through secure channels if possible. An example would be to customize your SageMaker AI image by installing dependencies, after they are code scanned, vetted technically and legally by your organization.
  2. If AWS PrivateLink integration is not available for external providers, allowlist network connections to these external sources. Allow firewall egress rules, directly or indirectly, through a proxy in your organization’s network. Check with your network administrator to understand the most appropriate option for your organization.

VPC Requirements

When setting up a new SageMaker Unified Studio Domain, it’s necessary to supply a VPC. It’s important to note that these VPC requirements are a union of all the requirements from the respective compute services integrated into Studio, some of which are reinforced by validation checks during the corresponding blueprint’s deployment. If these requirements that have validation checks are not fulfilled, the resource(s) contained in that blueprint may fail to create on project creation (on-create), or when creating the compute resource (on-demand). This section will present a summary of these requirements, as well as relevant documentation links from which they originate.

Subnet requirements for specific compute in a VPC

This section lists the compute services integrated in SageMaker Unified Studio that require VPC/subnets when provisioning the respective compute resources.

Compute Connections

Other Services

Requirements

  1. Number of subnets: At least two private subnets. This requirement comes from Redshift Serverless.
  2. Availability zones (AZs): At least two different AZs (for Regions with two AZs, two subnets are sufficient). This requirement comes from Redshift Serverless. For workgroups with Enhanced VPC Routing (EVR), you need three AZs.
  3. Free IPs per subnet: At least three Ips per subnet. This requirement comes from Redshift Serverless without EVR. For detailed IP addresses requirement with EVR enabled workgroups, refer to Serverless usage considerations. Three is a minimum and may not be enough for your needs. For example, EMR cluster creation will fail if no subnets with enough IPs are found in the VPC. We recommend doing a forward-looking capacity planning exercise based on your use cases (for example, growth rate, users, compute needs) to project at least 5 years into the future. This helps to determine how many IPs are needed by the team using Studio and other services that use this VPC and come up with a ceiling for the CIDR block size.
  4. Private or public subnets: We enforce that at least three private subnets be supplied, and recommend that only private subnets are chosen, with a few nuances. This requirement comes from SageMaker AI domain. A new SageMaker AI domain, when set up with VpcOnly mode, requires that all subnets in the VPC be private. This is the default networking mode in the Tooling blueprint. If you choose to use PublicInternetOnly mode, this restriction does not apply, you may choose public subnets from your VPC. To change the mode, modify the Tooling Blueprint parameter sagemakerDomainNetworkType.
  5. Enable DNS hostname and DNS Support: Both must be enabled. This requirement comes from EMR. Without these VPC settings, enableDnsHostname and enableDnsSupport, connecting to the EMR Cluster using the private DNS name through the Livy Endpoint will fail. SSL Verification, which can only be done when connecting using the DNS name, not the IP.
  6. Auto assign public IP: Disable. We recommend that this EC2 subnet setting (mapPublicIpOnLaunch) be disabled when using private subnets, because public IPs come at a cost and are a scarce resource in the total addressable IPv4 space.

VPC endpoints

If you choose to run SageMaker Unified Studio without public internet access, VPC endpoints are required for all services SageMaker Unified Studio needs to access. These endpoints provide secure, private connectivity between your VPC and AWS services without traversing the public internet. The following table lists the required endpoints, their types, and what each is used for.

Some endpoints may not show up directly in your browser’s network tab. The reason is that some of these services (such as CloudWatch) are transitively invoked by other services.

Mandatory endpoints

The following are required endpoints for SageMaker Unified Studio and supporting services to function properly. Gateway endpoints can be used where available, you can use interface endpoints for all other AWS services.

AWS service Endpoint Type Purpose
Glue
com.amazonaws.${region}.glue

Interface For Data Catalog and metadata management
STS
com.amazonaws.${region}.sts

Interface Required for assuming IAM roles
S3
com.amazonaws.${region}.s3

Gateway Required for datasets, Git backups, notebooks, and Git sync
SageMaker
com.amazonaws.${region}.sagemaker.api

Interface Required for calling SageMaker APIs
com.amazonaws.${region}.sagemaker.runtime

Interface For invoking deployed inference endpoints
DataZone
com.amazonaws.${region}.datazone

Interface For data catalog and governance
Secrets Manager
com.amazonaws.${region}.secretsmanager

Interface To securely access secrets
SSM
com.amazonaws.${region}.ssm

Interface For secure command execution
com.amazonaws.${region}.ssmmessages

Interface Enables live SSM sessions
KMS
com.amazonaws.${region}.kms

Interface For decrypting data (volumes, S3, secrets)
EC2
com.amazonaws.${region}.ec2

Interface For subnet and ENI management
com.amazonaws.${region}.ec2messages

Interface Required for SSM messaging
Athena
com.amazonaws.${region}.athena

Interface Required to run SQL queries
Amazon Q
com.amazonaws.${region}.q

Interface Used by SageMaker Notebooks for enhanced productivity

Optional Endpoints

Only create these if the corresponding service is used in your environment.

AWS service Endpoint Type Purpose
EMR
com.amazonaws.${region}.emr-serverless

Interface Serverless Spark/Hive jobs
com.amazonaws.${region}.emr-serverless-services.livy

Interface Required for Livy job submission (EMR Serverless)
com.amazonaws.${region}.elasticmapreduce

Interface Classic EMR (EC2-based)
com.amazonaws.${region}.emr-containers

Interface EMR on EKS workloads
Redshift
com.amazonaws.${region}.redshift

Interface For provisioned Redshift clusters
com.amazonaws.${region}.redshift-serverless

Interface For Redshift Serverless
com.amazonaws.${region}.redshift-data

Interface Required for running SQL against Redshift
Amazon Bedrock
com.amazonaws.${region}.bedrock-runtime

Interface Invoke Bedrock models at runtime
com.amazonaws.${region}.bedrock-agent

Interface For Bedrock knowledge agents
com.amazonaws.${region}.bedrock-agent-runtime

Interface For running knowledge agent workloads
CloudWatch
com.amazonaws.${region}.logs

Interface Application and notebook logs
RDS
com.amazonaws.${region}.rds

Interface Connect to Amazon RDS and Aurora
CodeCommit
com.amazonaws.${region}.codecommit

Interface Git integration with CodeCommit
com.amazonaws.${region}.git-codecommit

Interface Alternative endpoint for CodeCommit
CodeConnections and CodeStar
com.amazonaws.${region}.codeconnections.api

Interface GitHub and GitLab repo integration
com.amazonaws.${region}.codestar-connections.api

Interface Alias of CodeConnections

Clean up

AWS resources provisioned in your AWS accounts may incur costs based on the resources consumed. Make sure you do not leave any unintended resources provisioned. If you created a VPC and subsequent resources as part of this post, make sure you delete them.

The following service resources provisioned during this blog post need to be deleted:

  • IAM Identity Center users and groups.
  • Resources provisioned within your project using tooling configuration and blueprints within your domain.
  • The airgapped VPC.

Conclusion

In this post, we walked through the process of using your own existing VPC when creating domains and projects in SageMaker Unified Studio. This approach benefits customers by giving them greater control over their network infrastructure while using the comprehensive data, analytics, and AI/ML capabilities of Amazon SageMaker. We also explored the critical role of VPC endpoints in this set up. You now understand when these become necessary components of your architecture, particularly in scenarios requiring enhanced security, compliance with data residency requirements, or improved network performance.

While using a custom VPC requires more initial set up than the Quick Create option, it provides the flexibility and control many organizations need for their data science and analytics workflows. This approach provides a mechanism for your SageMaker environment to integrate with your existing infrastructure and adheres to your organization’s networking policies. Custom VPC configurations are a powerful tool in your arsenal for building secure, compliant, and efficient data science environments.

To learn more, visit Amazon SageMaker Unified Studio – Administrator Guide and User Guide.


About the authors

Saurabh Bhutyani

Saurabh Bhutyani

Saurabh is a Principal Analytics Specialist Solutions Architect at AWS. He is passionate about new technologies. He joined AWS in 2019 and works with customers to provide architectural guidance for running generative AI use cases, scalable analytics solutions and data mesh architectures using AWS services like Amazon Bedrock, Amazon SageMaker, Amazon EMR, Amazon Athena, AWS Glue, AWS Lake Formation, and Amazon DataZone.

Rohit Vashishtha

Rohit Vashishtha

Rohit is a Senior Analytics Specialist Solutions Architect at AWS based in Dallas, Texas. He has two decades of experience architecting, building, leading, and maintaining big data platforms. Rohit helps customers modernize their analytic workloads using the breadth of AWS services and ensures that customers get the best price/performance with utmost security and data governance.

Baggio Wong

Baggio is a Software Engineer on the SageMaker Unified Studio team, where he designs and delivers experiences that empower data practitioners to build and deploy AI/ML workloads.

Designing centralized and distributed network connectivity patterns for Amazon OpenSearch Serverless – Part 2

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/big-data/designing-centralized-and-distributed-network-connectivity-patterns-for-amazon-opensearch-serverless-part-2/

This post is Part 2 of our two-part series on hybrid multi-account access patterns for Amazon OpenSearch Serverless. In Part 1, we explored a centralized architecture where a single account hosts multiple OpenSearch Serverless collections and a shared VPC endpoint. This approach works well when a single business unit or team manages collections on behalf of the organization.

However, many enterprises have multiple business units that need independent ownership of their OpenSearch Serverless infrastructure. When each business unit wants to manage their own collections, security policies, and VPC endpoints within their own AWS accounts, the centralized model from Part 1 no longer fits.

In this post, we address this multi-business unit scenario by introducing a pattern where the central networking account manages a custom private hosted zone (PHZ) with CNAME records pointing to each business unit’s VPC endpoint. This approach maintains centralized DNS management and connectivity while giving each business unit full autonomy over their collections and infrastructure.

The challenge with multiple business units

When multiple business units independently manage their own OpenSearch Serverless collections in separate AWS accounts, each account has its own VPC endpoint with its own private hosted zones. These private hosted zones only work within their respective VPCs, creating DNS fragmentation across the organization. Consumers in spoke accounts and on-premises environments can’t resolve collection endpoints in other accounts without additional DNS configuration.

Managing individual PHZ associations for each consumer VPC doesn’t scale, and asking each business unit to coordinate DNS with every consumer creates operational overhead. You need a network architecture that gives each team autonomy while keeping DNS management and connectivity centralized.

Solution overview

This architecture solves the problem by centralizing DNS management in the networking account while leaving collection and VPC endpoint ownership with each business unit. The networking account maintains a custom PHZ with CNAME records that map each collection endpoint to the regional DNS name of its corresponding VPC endpoint. This custom PHZ is associated with a Route 53 Profile and shared through AWS Resource Access Manager (AWS RAM) to spoke accounts. On-premises DNS resolution flows through the Route 53 Resolver inbound endpoint in the central networking VPC, which uses the same custom PHZ.

We cover two complementary patterns: Pattern 1 for on-premises access to collections across multiple business unit accounts, and Pattern 2 for spoke account access to those same collections. Both patterns rely on the centralized custom PHZ managed by your networking team.

Pattern 1: On-premises access to OpenSearch Serverless collections across multiple business unit accounts

With this pattern, your on-premises clients can privately access OpenSearch Serverless collections hosted across multiple business unit accounts, each with its own VPC endpoint. The following diagram illustrates this multi-business-unit architecture. It shows how on-premises DNS queries are resolved through the custom PHZ in the central networking account and routed to the correct business unit’s VPC endpoint through AWS PrivateLink.

(A) The Route 53 Profiles are created in the central networking account and shared through AWS Resource Access Manager (AWS RAM) with the central OpenSearch Serverless account.

(B) The central networking account has a custom PHZ with domain us-east-1.aoss.amazonaws.com and associated with central networking account VPC and with Route 53 Profiles.

(C) This PHZ contains CNAME records pointing to each business unit’s VPC endpoints.

(D) Each business unit account has Private DNS enabled on its VPC endpoint.

(E) This automatically creates the following PHZs during VPC endpoint creation and associates them with the business unit’s VPC, so DNS resolution works locally within that VPC without depending on the Route 53 Profiles.

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

DNS resolution flow

  1. Your on-premises client initiates a request to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com.
  2. The on-premises DNS resolver has a conditional forwarder for us-east-1.aoss.amazonaws.com and forwards the query over AWS Direct Connect or AWS Site-to-Site VPN to the Route 53 Resolver inbound endpoint IPs in the central networking VPC.
  3. The inbound Resolver endpoint passes the query to the Route 53 VPC Resolver in the central networking VPC.
  4. The VPC Resolver finds the custom PHZ (bu-1-collection-id-1.us-east-1.aoss.amazonaws.com) associated with the central networking VPC. The CNAME record for bu-1-collection-id-1.us-east-1.aoss.amazonaws.com resolves to the regional DNS name of BU1’s VPC endpoint (for example, vpce-1234567890abcdefghi.a2oselk.vpce-svc-0c3ebf9a1a3ad247b.us-east-1.vpce.amazonaws.com).
  5. The VPC Resolver then resolves the VPC endpoint regional DNS name to its elastic network interfaces (ENIs) private IP addresses.
  6. The traffic reaches BU1’s VPC endpoint elastic network interfaces (ENIs) through private network connectivity because the on-premises client connects over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.

Data flow

  1. Your on-premises client sends an HTTPS request to the resolved IP address with the TLS Server Name Indication (SNI) header set to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com, over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.
  2. Traffic reaches the VPC endpoint ENIs in BU1’s OpenSearch Serverless VPC.
  3. The VPC endpoint forwards the request to the OpenSearch Serverless service, which inspects the hostname and routes to BU1 Collection 1.

To access a collection in BU2, your client follows the same flow using bu-2-collection-id-1.us-east-1.aoss.amazonaws.com. The custom PHZ contains a separate CNAME record pointing to BU2’s VPC endpoint, and the OpenSearch Serverless service routes to the correct collection based on the hostname.

Pattern 2: Spoke account access to OpenSearch Serverless collections across multiple business unit accounts

While Pattern 1 addresses on-premises access, you might also need to provide access from compute resources and distributed applications in spoke accounts to OpenSearch Serverless collections across multiple business unit accounts. With this pattern, compute resources in spoke account VPCs can privately access OpenSearch Serverless collections across multiple business unit accounts through the centralized private hosted zone (PHZ) in the networking account.

In the following example, we use an Amazon Elastic Compute Cloud (Amazon EC2) instance as a compute resource to illustrate the pattern. However, the same approach applies to any compute resource within the spoke VPC. The following diagram illustrates this multi-business-unit, multi-spoke architecture, showing how spoke VPCs resolve DNS through the shared Route 53 Profile and custom PHZ, then route traffic to the correct business unit’s OpenSearch Serverless collections through AWS PrivateLink.

(A) The Route 53 Profiles, created in the central networking account, are shared through AWS RAM with all spoke accounts and with the central OpenSearch Serverless account.

(B) The central networking account has a custom PHZ with domain us-east-1.aoss.amazonaws.com and associated with central networking account VPC and with Route 53 Profiles.

(C) This PHZ contains CNAME records pointing to each business unit’s VPC endpoints.

(D) Each business unit account has Private DNS enabled on its VPC endpoint.

(E) This automatically creates the following PHZs during VPC endpoint creation and associates them with the business unit’s VPC, so DNS resolution works locally within that VPC without depending on the Route 53 Profiles.

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

DNS resolution flow

  1. An Amazon EC2 instance in BU1 Spoke VPC 1 initiates a request to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com and sends a DNS query to the Route 53 VPC Resolver.
  2. The VPC Resolver finds the Route 53 Profiles associated with the spoke VPC.
  3. The Profiles reference the custom PHZ (us-east-1.aoss.amazonaws.com) managed in the central networking account. The CNAME record for bu-1-collection-id-1.us-east-1.aoss.amazonaws.com resolves to the regional DNS name of BU1’s VPC endpoint.
  4. The VPC Resolver then resolves the VPC endpoint regional DNS name to its elastic network interfaces (ENIs) private IP addresses.
  5. Traffic reaches the VPC endpoint ENIs through private network connectivity because the spoke VPC connects to BU1’s VPC through AWS Transit Gateway or AWS Cloud WAN.

Data flow

  1. Your Amazon EC2 instance sends an HTTPS request to the resolved IP address with the TLS SNI header set to bu-1-collection-id-1.us-east-1.aoss.amazonaws.com, routed through AWS Transit Gateway or AWS Cloud WAN to BU1’s OpenSearch Serverless VPC.
  2. The request arrives at the VPC endpoint ENIs in BU1’s OpenSearch Serverless VPC.
  3. The VPC endpoint forwards the request to the OpenSearch Serverless service, which inspects the hostname and routes to BU1 Collection 1.

To access a collection in BU2, the same flow applies using bu-2-collection-id-1.us-east-1.aoss.amazonaws.com. The custom PHZ resolves to BU2’s VPC endpoint, and routes traffic through the transit gateway to BU2’s VPC. The same applies to resources in other spoke accounts with the Route 53 Profiles associated.

Custom PHZ record structure

The custom PHZ in the central networking account uses the domain us-east-1.aoss.amazonaws.com and contains CNAME records that map each collection endpoint to the regional DNS name of its corresponding VPC endpoint. Note that collections within the same business unit account share the same VPC endpoint, so their CNAME records point to the same regional DNS name. Collections in different business unit accounts point to different VPC endpoints.

Custom PHZ management

Unlike Part 1, where the auto-created PHZs from the VPC endpoint handle DNS resolution, this pattern requires your networking team to manually maintain the custom PHZ. When a business unit adds a new collection, the networking team must add a corresponding CNAME record to the custom PHZ.

Cost considerations

The architecture patterns described in this post use several AWS services that can contribute to your overall costs, including Amazon Route 53 (hosted zones, DNS queries, and Resolver endpoints), and Route 53 Profiles. We recommend reviewing the official AWS pricing pages for the most current rates:

For a full cost estimate tailored to your workload, use the AWS Pricing Calculator.

Conclusion

In this post, we showed how you can give on-premises clients and spoke account resources private access to OpenSearch Serverless collections distributed across multiple business unit accounts. By centralizing DNS management through a custom PHZ in the networking account and sharing it through Route 53 Profiles, you avoid coordinating PHZ associations across accounts while giving each business unit full ownership of their collections and VPC endpoints.

Combined with Part 1, you now have two architectural approaches for hybrid multi-account access to OpenSearch Serverless: a centralized model where one account owns all collections and a shared VPC endpoint, and a distributed model where multiple business units each manage their own collections and VPC endpoints. Choose the centralized model when a single team manages collections on behalf of the organization. Choose the distributed model when business units need independent ownership of their OpenSearch Serverless infrastructure.

For additional details, refer to the Amazon OpenSearch Serverless VPC endpoint documentation and Route 53 Profiles documentation.
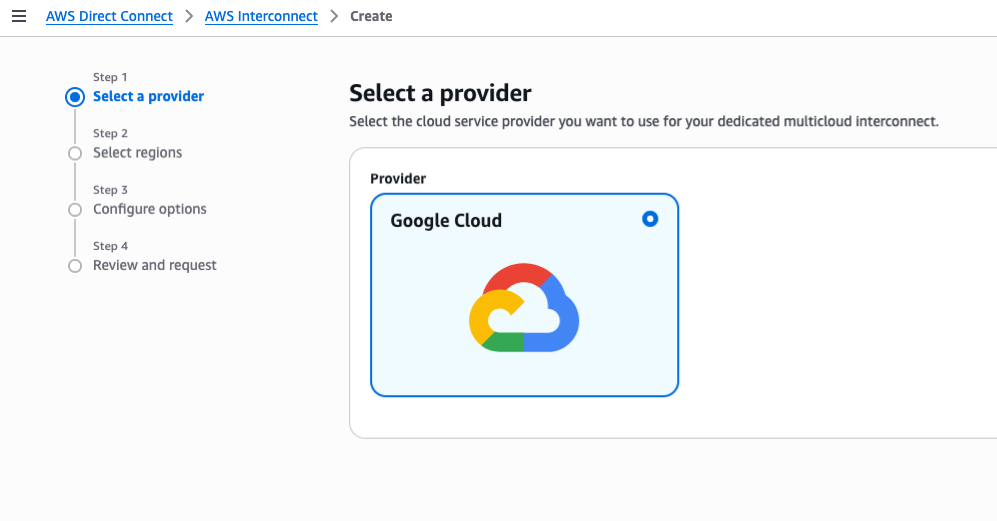

About the authors

Ankush Goyal

Ankush Goyal

Ankush is a Senior Technical Account Manager at AWS Enterprise Support, specializing in helping customers in the travel and hospitality industries optimize their cloud infrastructure. With over 20 years of IT experience, he focuses on leveraging AWS networking services to drive operational efficiency and cloud adoption. Ankush is passionate about delivering impactful solutions and enabling clients to streamline their cloud operations.

author name

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS. He specializes in guiding customers through the design, implementation, and support of AWS solutions. Combining his networking expertise with a drive to explore new technologies, he helps organizations successfully navigate their cloud journey. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Designing centralized and distributed network connectivity patterns for Amazon OpenSearch Serverless – Part 1

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/big-data/designing-centralized-and-distributed-network-connectivity-patterns-for-amazon-opensearch-serverless-part-1/

Amazon OpenSearch Serverless is a fully managed, serverless option for Amazon OpenSearch Service that removes the operational complexity of provisioning, configuring, and tuning OpenSearch clusters. When you run OpenSearch Serverless collections in a central account and need secure, private access from both on-premises environments and multiple AWS accounts, network architecture becomes critical. In this post, we explore two patterns to help you achieve this connectivity securely.

Solution overview

Working with customers implementing OpenSearch Serverless, we published blog posts addressing various network connectivity patterns to meet their evolving requirements:

In this post, we build on those patterns to address an additional enterprise requirement. When you manage many OpenSearch Serverless collections centrally but need access from multiple accounts and on-premises, you face several key challenges:

  • Coordinating VPC endpoints across accounts: managing endpoint provisioning and lifecycle across many consumer accounts adds operational overhead
  • Managing DNS configurations for each consumer: each new account or on-premises environment requires its own DNS setup, increasing complexity
  • Separating networking responsibilities from application ownership: without clear boundaries, networking and application teams become tightly coupled, slowing down both

This architecture solves these challenges with a clear separation of responsibilities. The central networking account shares Route 53 Profiles to manage DNS propagation across spoke accounts. The OpenSearch Serverless account owner maintains full control over their VPC endpoint and the associated private hosted zones (PHZs). Application owners retain autonomy over DNS configuration and collection management.

A single VPC endpoint handles multiple OpenSearch Serverless collections in an AWS Region, which reduces complexity and cost. Your networking team manages connectivity infrastructure while your application teams independently manage their OpenSearch Serverless collections, data access policies, and collection-specific DNS configurations. This gives you connectivity from on-premises networks (through AWS Direct Connect or AWS Site-to-Site VPN) and from compute resources across multiple AWS accounts through a unified network path.

This separation means that your network administrators and application teams can work independently. The result is a governance model that scales with your organization. We cover two complementary patterns that together give you complete hybrid access coverage, Pattern 1 for on-premises access and Pattern 2 for multi-account access, both using centralized interface VPC endpoints and Route 53 Profiles.

Before proceeding, you should be familiar with OpenSearch Serverless interface VPC endpoint DNS resolution. When creating an OpenSearch Serverless interface VPC endpoint, AWS automatically provisions four private hosted zones. The zones are three visible private hosted zones (for collections, dashboards, and FIPS endpoints) and one hidden internal private hosted zone that work together to resolve collection endpoints to private IP addresses. For more details on this DNS resolution mechanism, customers can review our previous blog post.

Pattern 1: Accessing multiple OpenSearch Serverless collections from on-premises through a centralized VPC endpoint and Route 53 Profiles in a multi-account architecture

The architecture spans three components:

  • A central OpenSearch Serverless account that hosts the collections and interface VPC endpoint.
  • A central networking account that owns the Route 53 Profiles and Inbound Resolver.
  • An on-premises environment connected using AWS Direct Connect or AWS Site-to-Site VPN.

The following diagram illustrates the architecture across these three components. It shows how DNS queries from on-premises clients are resolved through the Route 53 Profile and Inbound Resolver, and how data traffic reaches the OpenSearch Serverless collections using AWS PrivateLink.

(A) The Route 53 Profiles are created in the central networking account and shared through AWS Resource Access Manager (AWS RAM) with the central OpenSearch Serverless account. The central OpenSearch Serverless account associates the PHZs and interface VPC endpoint association with the shared Route 53 Profiles because that’s needed for end-to-end private DNS resolution.

(B) The central AOSS VPC contains an interface VPC endpoint for OpenSearch Serverless with Private DNS enabled. There are four Private Hosted Zones (PHZs):

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

(C) The first three PHZs must be manually associated with the Route 53 Profile.

(D) The fourth is automatically associated when the VPC endpoint is associated with the profile.

(E) On the on-premises side, the DNS resolver is configured with conditional forwarding for us-east-1.aoss.amazonaws.com, directing queries to the Route 53 Resolver Inbound Endpoint in the central networking account.

DNS resolution flow

  1. Your on-premises client initiates a request to collection-id-1.us-east-1.aoss.amazonaws.com.
  2. The on-premises DNS resolver has a conditional forwarder for us-east-1.aoss.amazonaws.com and forwards the query over AWS Direct Connect or AWS Site-to-Site VPN to the Route 53 Resolver inbound endpoint IPs in the central networking VPC.
  3. The inbound resolver receives the query and passes it to the Route 53 VPC Resolver.
  4. The VPC Resolver checks the Route 53 Profiles associated with the central networking VPC. The Profiles provide access to the visible and hidden PHZs from the central OpenSearch Serverless VPC.
  5. The VPC Resolver uses the visible PHZ to match the wildcard CNAME *.us-east-1.aoss.amazonaws.com to the interface VPC endpoint (VPCE) DNS name. It then uses the hidden PHZ to resolve the VPCE DNS name to the private elastic network interface (ENI) IP addresses of the interface VPC endpoint in the central OpenSearch Serverless VPC.
  6. The private ENI IP addresses are returned through the inbound resolver endpoint to the on-premises DNS resolver and back to the on-premises client.

Data flow

  1. The on-premises client sends an HTTPS request to the resolved private ENI IP address with the TLS Server Name Indication (SNI) header set to collection-id-1.us-east-1.aoss.amazonaws.com, over AWS Direct Connect or AWS Site-to-Site VPN through AWS Transit Gateway or AWS Cloud WAN.
  2. Traffic reaches the interface VPC endpoint ENIs in the central OpenSearch Serverless VPC.
  3. The interface VPC endpoint forwards the request to the OpenSearch Serverless service, which routes to Collection 1.

To access Collection 2, the client follows the same flow using collection-id-2.us-east-1.aoss.amazonaws.com. The wildcard DNS resolves to the same interface VPC endpoint, and the OpenSearch Serverless service routes to the correct collection based on the hostname.

Pattern 2: Accessing multiple OpenSearch Serverless collections from spoke accounts using a centralized VPC endpoint and Route 53 Profiles

While Pattern 1 addresses on-premises access, you might also need to provide access from compute resources and distributed applications across multiple AWS accounts. With this pattern, any compute resource running within spoke account VPCs can privately access multiple OpenSearch Serverless collections hosted in a central OpenSearch Serverless VPC through a single shared interface VPC endpoint.

In the following example, we use an Amazon Elastic Compute Cloud (Amazon EC2) instance as a compute resource to illustrate the pattern. However, the same approach applies to any compute resource within the spoke VPC.

The following diagram illustrates this multi-account architecture, showing how spoke account VPCs resolve DNS and route data traffic to the central OpenSearch Serverless collections through the shared Route 53 Profile and AWS PrivateLink, alongside the on-premises access path from Pattern 1.

(A) The Route 53 Profiles, created in the central networking account, are shared via AWS RAM with both the OpenSearch Serverless account and the spoke accounts. The OpenSearch Serverless account associates its interface VPC endpoint and private hosted zones (PHZs) with the Profiles, while each spoke account associates the Profiles with its VPC. Spoke VPCs get full DNS resolution for OpenSearch Serverless collection endpoints without requiring their own interface VPC endpoints, PHZs, or manual DNS configuration.

(B) The central AOSS VPC contains an interface VPC endpoint for OpenSearch Serverless with Private DNS enabled. There are four Private Hosted Zones (PHZs):

  • us-east-1.aoss.amazonaws.com
  • us-east-1.opensearch.amazonaws.com
  • us-east-1.aoss-fips.amazonaws.com
  • privatelink.c0X.sgw.iad.prod.aoss.searchservices.aws.dev

(C) The first three PHZs must be manually associated with the Route 53 Profile.

(D) The fourth is automatically associated when the VPC endpoint is associated with the profile.

DNS resolution flow

  1. An Amazon EC2 instance in Spoke VPC 1 initiates a request to collection-id-1.us-east-1.aoss.amazonaws.com and sends a DNS query to the Route 53 VPC Resolver.
  2. The VPC Resolver finds the Route 53 Profiles associated with the spoke VPC, which carries the PHZs from the central OpenSearch Serverless account.
  3. The visible PHZ matches the wildcard CNAME *.us-east-1.aoss.amazonaws.com to the VPCE DNS name. The hidden PHZ resolves the VPCE DNS name to the private ENI IP addresses of the interface VPC endpoint in the central OpenSearch Serverless VPC.
  4. Route 53 returns the private ENI IP addresses to the Amazon EC2 instance.

Data flow

  1. Your Amazon EC2 instance sends an HTTPS request to the resolved private ENI IP address with the TLS SNI header set to collection-id-1.us-east-1.aoss.amazonaws.com. This is routed through AWS Transit Gateway or AWS Cloud WAN to the central OpenSearch Serverless VPC.
  2. The request arrives at the interface VPC endpoint ENIs in the central OpenSearch Serverless VPC.
  3. The interface VPC endpoint forwards the request to the OpenSearch Serverless service, which routes to Collection 1.

To access Collection 2, the same flow applies using collection-id-2.us-east-1.aoss.amazonaws.com. The same applies to resources in Spoke Account 2 or other spoke accounts with the Route 53 Profiles associated.

AWS RAM Permission Configuration for Resource Association

When the central networking account shares the Route 53 Profiles through AWS RAM, the default AWS managed permissions policy (AWSRAMPermissionRoute53ProfileAllowAssociationActions) only grants actions for associating and disassociating the Profile with VPCs, viewing Profiles details, and listing associations. It does not include the route53profiles:AssociateResourceToProfile or route53profiles:DisassociateResourceFromProfile actions required for the OpenSearch Serverless account to associate its interface VPC endpoint and PHZs with the shared Profiles.

To enable this, the central networking account must create a custom managed permission in AWS RAM with the following actions:

  • route53profiles:AssociateProfile
  • route53profiles:AssociateResourceToProfile
  • route53profiles:DisassociateProfile
  • route53profiles:DisassociateResourceFromProfile
  • route53profiles:GetProfile
  • route53profiles:GetProfileResourceAssociation
  • route53profiles:ListProfileAssociations
  • route53profiles:ListProfileResourceAssociations
  • route53profiles:ListProfiles

This custom permission must be attached to the RAM resource share before the central OpenSearch Serverless account can associate its PHZs and interface VPC endpoint with the Profiles.

Cost considerations

The architecture patterns described in this post use several AWS services that may contribute to your overall costs, including Amazon Route 53 (hosted zones, DNS queries, and Resolver endpoints), and Route 53 Profiles. We recommend reviewing the official AWS pricing pages for the most current rates:

For a full cost estimate tailored to your workload, use the AWS Pricing Calculator.

Conclusion

In this post, we showed how organizations can provide secure, private access to multiple OpenSearch Serverless collections from both on-premises environments and distributed AWS accounts using a single centralized interface VPC endpoint and Route 53 Profiles. This architecture centralizes OpenSearch Serverless collections and network infrastructure in a dedicated account, using Route 53 Profiles to propagate DNS across accounts. This eliminates per-account VPC endpoints, manual PHZ associations, and custom DNS configuration in spoke accounts.

This pattern is a good fit when a single team or business unit manages OpenSearch Serverless collections centrally. However, many enterprises have business units that need to independently manage their own OpenSearch Serverless collections in separate AWS accounts, each with their own interface VPC endpoints, security policies, and collection lifecycle. In Part 2, we explore how the architecture changes to support this distributed ownership model, where each business unit runs OpenSearch Serverless in their own account while still relying on centralized network connectivity and DNS management through Route 53 Profiles. We will cover how DNS resolution and the Route 53 Profiles configuration adapt when interface VPC endpoints and collections are spread across multiple accounts.

For additional details, refer to the OpenSearch Serverless VPC endpoint documentation and Route 53 Profiles documentation.
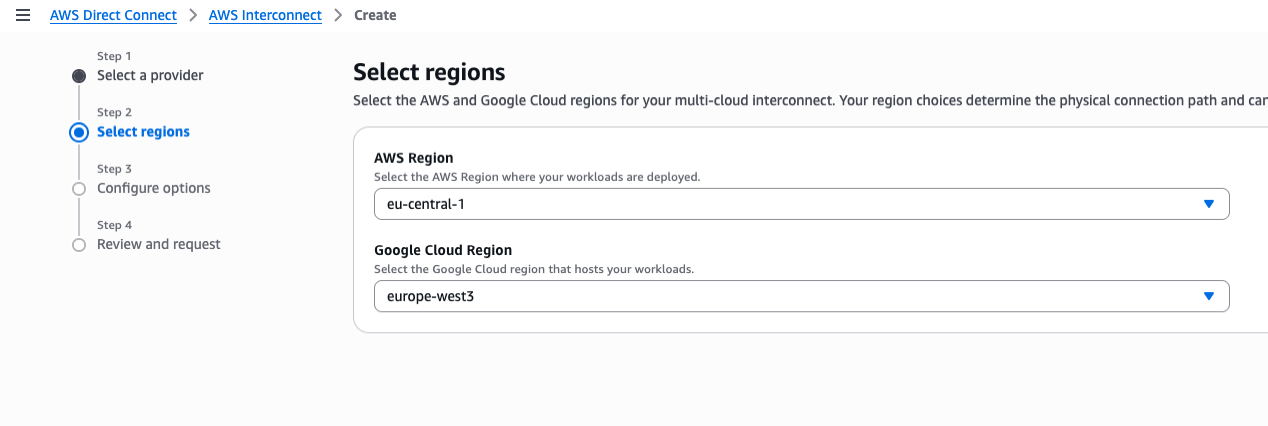

About the authors

Ankush Goyal

Ankush Goyal

Ankush is a Senior Technical Account Manager at AWS Enterprise Support, specializing in helping customers in the travel and hospitality industries optimize their cloud infrastructure. With over 20 years of IT experience, he focuses on leveraging AWS networking services to drive operational efficiency and cloud adoption. Ankush is passionate about delivering impactful solutions and enabling clients to streamline their cloud operations.

author name

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS. He specializes in guiding customers through the design, implementation, and support of AWS solutions. Combining his networking expertise with a drive to explore new technologies, he helps organizations successfully navigate their cloud journey. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

AWS Weekly Roundup: Amazon Connect Health, Bedrock AgentCore Policy, GameDay Europe, and more (March 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-connect-health-bedrock-agentcore-policy-gameday-europe-and-more-march-9-2026/

Fiti AWS Student Community Kenya!

Last week was an incredible whirlwind: a round of meetups, hands-on workshops, and career discussions across Kenya that culminated with the AWS Student Community Day at Meru University of Science and Technology, with keynotes from my colleagues Veliswa and Tiffany, and sessions on everything from GitOps to cloud-native engineering, and a whole lot of AI agent building.

JAWS Days 2026 is the largest AWS Community Day in the world, with over 1,500 attendees on March 7th. This event started with a keynote speech on building an AI-driven development team by Jeff Barr, and included over 100 technical and community experience sessions, lightning talks, and workshops such as Game Days, Builders Card Challenges, and networking parties.

Now, let’s get into this week’s AWS news…

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Introducing Amazon Connect Health, Agentic AI Built for Healthcare — Amazon Connect Health is now generally available with five purpose-built AI agents for healthcare: patient verification, appointment management, patient insights, ambient documentation, and medical coding. All features are HIPAA-eligible and deployable within existing clinical workflows in days.
  • Policy in Amazon Bedrock AgentCore is now generally available — You can now use centralized, fine-grained controls for agent-tool interactions that operate outside your agent code. Security and compliance teams can define tool access and input validation rules using natural language that automatically converts to Cedar, the AWS open-source policy language.
  • Introducing OpenClaw on Amazon Lightsail to run your autonomous private AI agents — You can deploy a private AI assistant on your own cloud infrastructure with built-in security controls, sandboxed agent sessions, one-click HTTPS, and device pairing authentication. Amazon Bedrock serves as the default model provider, and you can connect to Slack, Telegram, WhatsApp, and Discord.
  • AWS announces pricing for VPC Encryption Controls — Starting March 1, 2026, VPC Encryption Controls transitions from free preview to a paid feature. You can audit and enforce encryption-in-transit of all traffic flows within and across VPCs in a region, with monitor mode to detect unencrypted traffic and enforce mode to prevent it.
  • Database Savings Plans now supports Amazon OpenSearch Service and Amazon Neptune Analytics — You can save up to 35% on eligible serverless and provisioned instance usage with a one-year commitment. Savings Plans automatically apply regardless of engine, instance family, size, or AWS Region.
  • AWS Elastic Beanstalk now offers AI-powered environment analysis — When your environment health is degraded, Elastic Beanstalk can now collect recent events, instance health, and logs and send them to Amazon Bedrock for analysis, providing step-by-step troubleshooting recommendations tailored to your environment’s current state.
  • AWS simplifies IAM role creation and setup in service workflows — You can now create and configure IAM roles directly within service workflows through a new in-console panel, without switching to the IAM console. The feature supports Amazon EC2, Lambda, EKS, ECS, Glue, CloudFormation, and more.
  • Accelerate Lambda durable functions development with new Kiro power — You can now build resilient, long-running multi-step applications and AI workflows faster with AI agent-assisted development in Kiro. The power dynamically loads guidance on replay models, step and wait operations, concurrent execution patterns, error handling, and deployment best practices.
  • Amazon GameLift Servers launches DDoS Protection — You can now protect session-based multiplayer games against DDoS attacks with a co-located relay network that authenticates client traffic using access tokens and enforces per-player traffic limits, at no additional cost to GameLift Servers customers.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

From AWS community
Here are my personal favorite posts from AWS community and my colleagues:

  • I Built a Portable AI Memory Layer with MCP, AWS Bedrock, and a Chrome Extension — Learn how to build a persistent memory layer for AI agents using MCP and Amazon Bedrock, packaged as a Chrome extension that carries context across sessions and applications.
  • When the Model Is the Machine — Mike Chambers built an experimental app where an AI agent generates a complete, interactive web application at runtime from a single prompt — no codebase, no framework, no persistent state. A thought-provoking exploration of what happens when the model becomes the runtime.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Community GameDay Europe — Think you know AWS? Prove it at the AWS Community GameDay Europe on March 17, a gamified learning event where teams compete to solve real-world technical challenges using AWS services.
  • AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, and ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.
  • AWS Summits — Join AWS Summits in 2026: free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
  • AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include Slovakia (March 11), Pune (March 21), and the AWSome Women Summit LATAM in Mexico City (March 28)

Browse here for upcoming AWS led in-person and virtual events, startup events, and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

Introducing VPC encryption controls: Enforce encryption in transit within and across VPCs in a Region

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-vpc-encryption-controls-enforce-encryption-in-transit-within-and-across-vpcs-in-a-region/

Today, we’re announcing virtual private cloud (VPC) encryption controls, a new capability of Amazon Virtual Private Cloud (Amazon VPC) that helps you audit and enforce encryption in transit for all traffic within and across VPCs in a Region.

Organizations across financial services, healthcare, government, and retail face significant operational complexity in maintaining encryption compliance across their cloud infrastructure. Traditional approaches require piecing together multiple solutions and managing complex public key infrastructure (PKI), while manually tracking encryption across different network paths using spreadsheets—a process prone to human error that becomes increasingly challenging as infrastructure scales.

Although AWS Nitro based instances automatically encrypt traffic at the hardware layer without affecting performance, organizations need simple mechanisms to extend these capabilities across their entire VPC infrastructure. This is particularly important for demonstrating compliance with regulatory frameworks such as Health Insurance Portability and Accountability (HIPAA), Payment Card Industry Data Security Standard (PCI DSS), and Federal Risk and Authorization Management Program (FedRAMP), which require proof of end-to-end encryption across environments. Organizations need centralized visibility and control over their encryption status, without having to manage performance trade-offs or complex key management systems.

VPC encryption controls address these challenges by providing two operational modes: monitor and enforce. In monitor mode, you can audit the encryption status of your traffic flows and identify resources that allow plaintext traffic. The feature adds a new encryption-status field to VPC flow logs, giving you visibility into whether traffic is encrypted using Nitro hardware encryption, application-layer encryption (TLS), or both.

After you’ve identified resources that need modification, you can take steps to implement encryption. AWS services, such as Network Load Balancer, Application Load Balancer, and AWS Fargate tasks, will automatically and transparently migrate your underlying infrastructure to Nitro hardware without any action required from you and with no service interruption. For other resources, such as the previous generation of Amazon Elastic Compute Cloud (Amazon EC2) instances, you will need to switch to modern Nitro based instance types or configure TLS encryption at application level.

You can switch to enforce mode after all resources have been migrated to encryption-compliant infrastructure. This migration to encryption-compliant hardware and communication protocols is a prerequisite for enabling enforce mode. You can configure specific exclusions for resources such as internet gateways or NAT gateways, that don’t support encryption (because the traffic flows outside of your VPC or the AWS network).

Other resources must be encryption-compliant and can’t be excluded. After activation, enforce mode provides that all future resources are only created on compatible Nitro instances, and unencrypted traffic is dropped when incorrect protocols or ports are detected.

Let me show you how to get started

For this demo, I started three EC2 instances. I use one as a web server with Nginx installed on port 80, serving a clear text HTML page. The other two are continuously making HTTP GET requests to the server. This generates clear text traffic in my VPC. I use the m7g.medium instance type for the web server and one of the two clients. This instance type uses the underlying Nitro System hardware to automatically encrypt in-transit traffic between instances. I use a t4g.medium instance for the other web client. The network traffic of that instance is not encrypted at the hardware level.

To get started, I enable encryption controls in monitor mode. In the AWS Management Console, I select Your VPCs in the left navigation pane, then I switch to the VPC encryption controls tab. I choose Create encryption control and select the VPC I want to create the control for.

Each VPC can have only one VPC encryption control associated with it, creating a one-to-one relationship between the VPC ID and the VPC encryption control Id. When creating VPC encryption controls, you can add tags to help with resource organization and management. You can also activate VPC encryption control when you create a new VPC.

VPC Encryption Control - create EC 1

I enter a Name for this control. I select the VPC I want to control. For existing VPCs, I have to start in Monitor mode, and I can turn on Enforce mode when I’m sure there is no unencrypted traffic. For new VPCs, I can enforce encryption at the time of creation.

Optionally, I can define tags when creating encryption controls for an existing VPC. However, when enabling encryption controls during VPC creation, separate tags can’t be created for VPC encryption controls—because they automatically inherit the same tags as the VPC. When I’m ready, I choose Create encryption control.

VPC Encryption Control - create EC 2Alternatively, I can use the AWS Command Line Interface (AWS CLI):

aws ec2 create-vpc-encryption-control --vpc-id vpc-123456789

Next, I audit the encryption status of my VPC using the console, command line, or flow logs:

aws ec2 create-flow-logs \
  --resource-type VPC \
  --resource-ids vpc-123456789 \
  --traffic-type ALL \
  --log-destination-type s3 \
  --log-destination arn:aws:s3:::vpc-flow-logs-012345678901/vpc-flow-logs/ \
  --log-format '${flow-direction} ${traffic-path} ${srcaddr} ${dstaddr} ${srcport} ${dstport} ${encryption-status}'
{
    "ClientToken": "F7xmLqTHgt9krTcFMBHrwHmAZHByyDXmA1J94PsxWiU=",
    "FlowLogIds": [
        "fl-0667848f2d19786ca"
    ],
    "Unsuccessful": []
}

After a few minutes, I see this traffic in my logs:

flow-direction traffic-path srcaddr dstaddr srcport dstport encryption-status
ingress - 10.0.133.8 10.0.128.55 43236 80 1 # <-- HTTP between web client and server. Encrypted at hardware-level
egress 1 10.0.128.55 10.0.133.8 80 43236 1
ingress - 10.0.133.8 10.0.128.55 36902 80 1
egress 1 10.0.128.55 10.0.133.8 80 36902 1
ingress - 10.0.130.104 10.0.128.55 55016 80 0 # <-- HTTP between web client and server. Not encrypted at hardware-level
egress 1 10.0.128.55 10.0.130.104 80 55016 0
ingress - 10.0.130.104 10.0.128.55 60276 80 0
egress 1 10.0.128.55 10.0.130.104 80 60276 0
  • 10.0.128.55 is the web server with hardware-encrypted traffic, serving clear text traffic at application level.
  • 10.0.133.8 is the web client with hardware-encrypted traffic.
  • 10.0.130.104 is the web client with no encryption at the hardware level.

The encryption-status field tells me the status of the encryption for the traffic between the source and destination address:

  • 0 means the traffic is in clear text
  • 1 means the traffic is encrypted at the network layer (Level 3) by the Nitro system
  • 2 means the traffic is encrypted at the application layer (Level7, TCP Port 443 and TLS/SSL)
  • 3 means the traffic is encrypted both at the application layer (TLS) and the network layer (Nitro)
  • “-” means VPC encryption controls are not enabled, or AWS Flow Logs don’t have the status information.

The traffic originating from the web client on the instance that isn’t Nitro based (10.0.130.104), is flagged as 0. The traffic initiated from the web client on the Nitro- ased instance (10.0.133.8) is flagged as 1.

I also use the console to identify resources that need modification. It reports two nonencrypted resources: the internet gateway and the elastic network interface (ENI) of the instance that isn’t based on Nitro.

VPC Encryption Control - list of exclusionsI can also check for nonencrypted resources using the CLI:

aws ec2 get-vpc-resources-blocking-encryption-enforcement --vpc-id vpc-123456789

After updating my resources to support encryption, I can use the console or the CLI to switch to enforce mode.

In the console, I select the VPC encryption control. Then, I select Actions and Switch mode.

VPC Encryption Control - switch modeOr the equivalent CLI:

aws ec2 modify-vpc-encryption-control --vpc-id vpc-123456789 --mode enforce

How to modify the resources that are identified as nonencrypted?

All your VPC resources must support traffic encryption, either at the hardware layer or at the application layer. For most resources, you don’t need to take any action.

AWS services accessed through AWS PrivateLink and gateway endpoints automatically enforce encryption at the application layer. These services only accept TLS-encrypted traffic. AWS will automatically drop any traffic that isn’t encrypted at the application layer.

When you enable monitor mode, we automatically and gradually migrate your Network Load Balancers, Application Load Balancers, AWS Fargate clusters, and Amazon Elastic Kubernetes Service (Amazon EKS) clusters to hardware that inherently supports encryption. This migration happens transparently without any action required from you.

Some VPC resources require you to select the underlying instances that support modern Nitro hardware-layer encryption. These include EC2 Instances, Auto Scaling groups, Amazon Relational Database Service (Amazon RDS) databases (including Amazon DocumentDB), Amazon ElastiCache node-based clusters, Amazon Redshift provisioned clusters, EKS clusters, ECS with EC2 capacity, MSK Provisioned, Amazon OpenSearch Service, and Amazon EMR. To migrate your Redshift clusters, you must create a new cluster or namespace from a snapshot.

If you use newer-generation instances, you likely already have encryption-compliant infrastructure because all recent instance types support encryption. For older-generation instances that don’t support encryption-in transit, you’ll need to upgrade to supported instance types.

Something to know when using AWS Transit Gateway

When creating a Transit Gateway through AWS CloudFormation with VPC encryption enabled, you need two additional AWS Identity and Access Management (IAM) permissions: ec2:ModifyTransitGateway and ec2:ModifyTransitGatewayOptions. These permissions are required because CloudFormation uses a two-step process to create a Transit Gateway. It first creates the Transit Gateway with basic configuration, then calls ModifyTransitGateway to enable encryption support. Without these permissions, your CloudFormation stack will fail during creation when attempting to apply the encryption configuration, even if you’re only performing what appears to be a create operation.

Pricing and availability

You can start using VPC encryption controls today in these AWS Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Melbourne, Mumbai, Osaka, Singapore, Sydney, Tokyo), Canada (Central), Canada West (Calgary), Europe (Frankfurt, Ireland, London, Milan, Paris, Stockholm, Zurich), Middle East (Bahrain, UAE), and South America (São Paulo).

VPC encryption controls is free of cost until March 1, 2026. The VPC pricing page will be updated with details as we get closer to that date.

To learn more, visit the VPC encryption controls documentation or try it out in your AWS account. I look forward to hearing how you use this feature to strengthen your security posture and help you meet compliance standards.

— seb

How to update CRLs without public access using AWS Private CA

Post Syndicated from Rochak Karki original https://aws.amazon.com/blogs/security/how-to-update-crls-without-public-access-using-aws-private-ca/

Certificates and the hierarchy of trust they create are the backbone of a secure infrastructure. AWS Private Certificate Authority is a highly available certificate authority (CA) that you can use to create private CA hierarchies, secure your applications and devices with private certificates, and manage certificate lifecycles.

A certificate revocation list (CRL) is a file that contains a signed list of certificates revoked before their scheduled expiration date. Certificates can be revoked for a variety of reasons, including unintended key exposure, or because of discontinued use.

AWS Private CA writes CRLs to an Amazon Simple Storage Service (Amazon S3) bucket that you specify. CRLs are public, fully qualified domain names (FQDNs), but you might have requirements for a CRL that is only accessible internally to your organization, or you might have security standards that require all S3 buckets to have Amazon S3 block public access enabled.

The recommended practice for S3 buckets is to enable Block Public Access, which enables only authorized and authenticated AWS accounts to have access to a bucket and its contents. However, because some public key infrastructure (PKI) clients retrieve CRLs across the public internet, a workaround might be necessary to serve CRLs without requiring authenticated client access to an S3 bucket. One recommended solution is to use Amazon CloudFront to provide access to the CRL. This will likely be the best solution for most customers. Our documentation specifically highlights CloudFront as the recommended implementation path. However, you might not be able to use CloudFront or might need another option.

You might need a solution where the CRL lookups don’t traverse the public internet. In this post, we go over two different approaches to achieve this.

Option 1: Relocate CRLs to an internally accessible location

By default, AWS Private CA writes CRLs to an S3 bucket that you specify. This solution consists of moving the CRL to a separate location that is internally accessible to your TLS clients, but not accessible via the public internet such as an on-premises server. A CRL distribution point (CDP) is a link that points to the location of the CRL where revoked certificates appear. However, when private certificates are generated by AWS Certificate Manager (ACM), the CDP universal resource identifiers (URI) in the certificates point by default to the S3 bucket initially specified.

This solution uses a custom CNAME in the CDP to indicate, during certificate generation, the location where the CRL will ultimately be located.

The steps in the solution are as follows:

  1. Select the S3 bucket where the CRL will be stored.
  2. Issue a certificate through the CA with a custom CNAME.
  3. Create an AWS Lambda function that moves the CRL file from the S3 bucket to another specified location.
  4. Create an Amazon Simple Notification Service (Amazon SNS) notification that alerts a user to the success metric of the CRL generation event.

Prerequisites:

For this walkthrough, you must have the following resources ready to use:

  1. An AWS account with:
    • An AWS Identity and Access Management (IAM) role with permissions for Amazon S3, ACM Private CA, Amazon EventBridge, and Lambda
    • An ACM private CA root and subordinate CA configured in the same AWS Region
    • An S3 bucket for the CRL with permissions that allow the AWS Private CA service principal to PutObject, PutObjectACL, GetBucketACL and GetBucketLocation (see the following example bucket policy)
{     
    "Version": "2012-10-17",     
    "Statement": [         
        {             
            "Effect": "Allow",             
            "Principal": {                 
                "Service": "acm-pca.amazonaws.com"             
            },             
            "Action": [                 
                "s3:PutObject",                 
                "s3:PutObjectAcl",                 
                "s3:GetBucketAcl",                 
                "s3:GetBucketLocation"             
            ],             
            "Resource": [                 
                "arn:aws:s3:::<name-of-bucket>/*",                 
                "arn:aws:s3:::<name-of-bucket>"             
            ],             
            "Condition": {                 
                "StringEquals": {                     
                    "aws:SourceAccount": "<account-num-here>",                     
                    "aws:SourceArn": "<subordinate-ca-arn-here>"                 
                }             
            }         
        }     
    ] 
}

2. AWS Command Line Interface (AWS CLI) configured

Deploy:

With the prerequisites in place, you’re ready to deploy the first solution.

To enable CRL distribution:

  1. Use your account to sign in to the AWS Management Console for AWS Private Certificate Authority.
  2. Select the name of your subordinate CA. This should take you to another page with more details.
  3. Scroll down and choose the Revocation configuration tab.
  4. Choose Edit on the top right.
  5. Figure 1: Edit the revocation configuration

    Figure 1: Edit the revocation configuration

  6. Select Activate CRL distribution. Select the CRL S3 bucket you created prior to the walkthrough.
  7. Figure 2: Enter a name for your CRL

    Figure 2: Enter a name for your CRL

  8. Modify the CDP by expanding the CRL settings dropdown. In the Custom CRL Name field, enter the URL where you will eventually move the CRL. This should be a place that is accessible by your internal organization, but not accessible externally. If you use partitioned CRLs, select the Enable partitioning checkbox. To learn more about CRL partitioning, see Plan your AWS Private CA certificate revocation method.
  9. Choose Save changes.

To create an SNS topic and Lambda function:

  1. Go to the Amazon SNS console.
  2. Create a standard SNS topic. Leave all options as default and subscribe an appropriate email to the topic.
  3. Figure 3: Create an SNS topic

    Figure 3: Create an SNS topic

  4. Go to the Lambda console.
  5. Choose Create Function.
  6. Enter a name for your function. Under Runtime, select Python 3.12 from the dropdown.
  7. Figure 4: Create a Lambda function

    Figure 4: Create a Lambda function

  8. Verify that the role associated with your Lambda function has permissions to get objects from the S3 bucket where AWS Private CA places the CRL (set when you configured the revocation details for the CA), copy objects in Amazon S3, then put objects in an S3 bucket (or wherever the new CRL distribution point specified in the certificate custom CNAME will be—for example, an internal-only accessible location), and publish to an Amazon SNS topic. The Lambda function also checks the success metric of a CRL generation event. If the event fails, an SNS topic will notify an admin. If the event is successful, a copy of the CRL in the original S3 bucket is created in the new specified location and an SNS topic will notify an admin.

Example code (Python 3.13):

import boto3 
import json 

def lambda_handler(event, context):     
	#create a s3 client     
	s3 = boto3.client('s3')          

	#create a sns client     
	sns = boto3.client('sns')     
    topicArn = "<sns-topic-arn-here>”     
    
    #get name of the CA from the CW event     
    caID = event['resources'][0].split('/')[-1]          
    status = event['detail']['result']     
    if status == 'success':              
    	
        source = '<ORIGINS3BUCKET>'         
        destination = '<DESTINATION-S3BUCKET>'         
        #See below note for more clarification on S3 CRL paths         
        folder = 'crl/'         
        file = caID + '.crl'         
        key = folder + file              
        
        try:             
        	copySource = {                 
            	'Bucket': source,                 
                'Key': key             
           	}                      
            
            s3.copy_object(                 
            	CopySource=copySource,                 
                Bucket=destination,                 
                Key=file             
          	)             
            response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f'Successfully moved {key} from {source} to {destination} in {caID}',                 
                Subject="CRL Upload Success"             
          	)                      
            
            return {                 
            	'statusCode': 200,                 
                'body': json.dumps(f'Successfully moved {key} from {source} to {destination} in {caID}')             
          	}                  
    	
        except s3.exceptions.NoSuchKey:             
        	response = sns.publish(                 
            	TopicArn=<sns-topicArn>,                 
                Message=f"Object {key} not found in {source}",                 
                Subject='CRL Upload Failure'             
          	)             
            return {                 
            	'statusCode': 404,                 
                'body': json.dumps(f'Object {key} not found in {source}')             
          	}                  
   		except Exception as e:             
    		print(e)             
        	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Error moving object: {str(e)}',                 
            	Subject='Failure Uploading CRL'             
     		)             
			return {                 
    			'statusCode': 500,                 
        		'body': json.dumps(f'Error moving object: {str(e)}')             
  			}     
    else:         
    	response = sns.publish(                 
        		TopicArn=<sns-topicArn>,                 
            	Message=f'Certificate Authority {caID} CRL creation {status}',                 
            	Subject='CRL Upload Failure'             
     		)         
        return {             
        	'statusCode': 200,             
            'body': json.dumps(f'Certificate Authority {caID} CRL creation {status}')         
      	}

Note: By default, the non-partitioned CRL path in S3 is <s3-bucket-name>/crl/<CA-ID>.crl. If you used a custom path, modify the path name to the CRL accordingly. Alternatively, if using partitioned CRLs, the path changes to <s3-bucket-name>/crl/<CA-ID>/<partition_GUID>.crl; in that case, you can loop over each file in the <CA-ID> path to achieve the same effect.

To create an EventBridge that deploys your Lambda function:

  1. Go to the EventBridge console. Under Buses, select Rules.
  2. Choose Create Rule.
  3. Enter a name for your rule. Under Rule Type, select Rule with an Event Pattern and choose Next.
  4. Under Events, select AWS events or EventBridge partner events as the Event Source.
  5. For the Event pattern, select Use pattern form. For the Event source, select AWS services. For Event Type, select ACM Private CA CRL Generation.
Figure 5: Configure the event pattern

Figure 5: Configure the event pattern

  1. Choose Next.
  2. Under Target types, choose AWS Service, and then select Lambda function from the Select a target dropdown and select the function that you created earlier.
  3. Figure 6: Select the Lambda function as the target

    Figure 6: Select the Lambda function as the target

  4. Choose Next. Review your topic, then choose Update rule.
  5. To test the success of the Lambda function:

    1. To test the EventBridge topic, create and revoke a certificate. You can do this using the AWS CLI by getting the serial number of a certificate using openSSL:
      openssl x509 -in cert.pem -noout -serial
    2. Use the following command to revoke the certificate:
      aws acm-pca revoke-certificate —certificate-authority-arn <CA ARN> \ —certificate-serial <SERIAL NUMBER RETURNED IN STEP 1> --revocation-reason “UNSPECIFIED”
    3. To make sure that the Lambda function is triggered, wait 5–30 minutes. Check CloudTrail to make sure that RevokeCertificate was called, then monitor the CloudWatch log of the Lambda function. You should also get a notification message from your SNS topic.
    4. You have now successfully moved your CRL to a new location.

    Option 2: Implement Private CRL Access Through AWS Private CA

    This solution provides private Certificate CRL access within AWS Private CA, avoiding the need for public internet exposure. The design centers on establishing root and subordinate CAs with CRL functionality enabled within a dedicated S3 bucket, combined with a private network infrastructure using Gateway VPC endpoints and private subnets. Security is enforced through an S3 bucket policy that accomplishes three critical objectives:

    • Authorizing essential AWS Private CA permissions
    • Constraining CRL access to a designated Gateway VPC endpoint
    • Explicitly blocking access attempts from other sources.

    The solution includes private DNS zone configuration for proper resolution and can be verified through access testing confirming successful CRL retrieval from private VPC instances while making sure that requests from public instances are denied, maintaining a strictly private PKI.

    1. Create a root CA and subordinate CA with CRL enabled
    2. Configure a dedicated S3 bucket for CRL storage
    3. Issue private certificates through ACM
    4. Set up a VPC with private subnets
    5. Configure a Gateway VPC endpoint for Amazon S3
    6. Set up route tables for local traffic only
    7. Implement an S3 bucket policy with specific permissions
    8. Configure private DNS resolution
    9. Set up access controls through VPC endpoints
    10. Test private access from within the VPC
    11. Verify that public access is blocked

    Prerequisites for CRL solution 2

    For this walkthrough, you must have the following resources available:

    Deploy CRL solution 2

    With the prerequisites in place, you’re ready to use the console and AWS CLI to deploy the solution.

    To deploy the solution:

    1. Go to the AWS Private Certificate Authority console.
    2. In the navigation pane, choose Create a Private CA.
      1. Under Mode options, select General-purpose.
      2. For CA type options, select root.
      3. For the Subject distinguished name options: Fill in at least one of the subject distinguished name options: Organization(O), Organization unit (OU), Country(C), State, Locality name, and Common name (CN).
        Figure 7: Create a private CA (root)

        Figure 7: Create a private CA (root)

      4. Select Key algorithm options, for example, RSA 2046.
      5. Under Certificate revocation options, select Activate CRL Distribution, and select or create an S3 bucket for CRL storage.
      6. Under Pricing, select the checkbox to acknowledge pricing and then select Create CA.
    Figure 8: Configure a private CA (root)

    Figure 8: Configure a private CA (root)

    3. After creating a root CA, repeat all of step 2 to create a subordinate CA, selecting
    Subordinate CA under
    CA options (step 2-b). When completed, both the root CA and subordinate CA will be visible on the Private certificate authority page.

    Figure 9: View of root CA and subordinate CA

    Figure 9: View of root CA and subordinate CA

    With the root CA and subordinate CA in place, the next step is to create a VPC gateway endpoint for S3 access to enable private network communication.

    To create a VPC gateway endpoint:

    1. Go to the Amazon VPC console
    2. In the left navigation pane, select Endpoints, and choose Create Endpoint.
    3. Configure the Gateway VPC endpoint settings:
      1. Enter a descriptive name for your endpoint (optional).
      2. Type: Select AWS services.
      3. Services: Select the service name com.amazonaws.[region].s3 from the list.
      4. Type: Verify that Gateway is selected (automatically chosen for Amazon S3).
      5. VPC: Choose the VPC where you want to create the endpoint.
      6. Route tables: Select the route tables associated with the subnets that need Amazon S3 access.
      7. Policy: Select Full Access or create a custom policy to restrict access to specific S3 buckets or actions.
      8. Review your configuration and choose Create endpoint.
    Figure 10: Gateway VPC endpoint configuration

    Figure 10: Gateway VPC endpoint configuration

    1. Create two private subnets:
      1. In the Amazon VPC console, choose Subnets and then Create subnet.
      2. Select your VPC and enter the subnet details (name, Availability Zone, and CIDR block).
      3. Repeat for the second subnet in a different Availability Zone.
    2. Configure route tables:
      1. Navigate to Route Tables and choose Create route table.
      2. Create and name two route tables for your private subnets.
      3. Associate each route table with its corresponding private subnet.
      4. Make sure that each route table contains only local routes (VPC CIDR).
      5. Remove any routes for internet access (0.0.0.0/0).
    Figure 11: Private route table configuration

    Figure 11: Private route table configuration

    1. You can see now see under Resource Map that the Gateway VPC endpoint provides secure access to Amazon S3 resources within the private network.
    Figure 12: VPC private instance configuration

    Figure 12: VPC private instance configuration

    1. Use the following example code to implement a bucket policy that enforces the following key security controls:
      • Grant AWS Private CA the necessary permissions for certificate management.
      • Restrict CRL access exclusively through the specified VPC endpoint.
      • Explicitly deny GetObject requests not originating from the designated Gateway VPC endpoint.
    Figure 13: S3 bucket policy

    Figure 13: S3 bucket policy

    The following is an example S3 bucket policy for private CA CRL access with VPC endpoint restrictions:

    {     
        "Version": "2012-10-17",     
        "Statement": [         
            {             
                "Effect": "Allow",             
                "Principal": {                 
                    "Service": "acm-pca.amazonaws.com"             
                    },             
                "Action": [                 
                    "s3:PutObject",                 
                    "s3:PutObjectAcl",                 
                    "s3:GetBucketAcl",                 
                    "s3:GetBucketLocation"             
                ],             
                "Resource": [                 
                    "<arn:aws:s3:::BUCKET_NAME>",                 
                    "<arn:aws:s3:::BUCKET_NAME>/"           
                ],           
                "Condition": {               
                    "StringEquals": {                   
                        "aws:SourceArn": "<arn:aws:acm-pca:REGION:ACCOUNT_ID:certificate-authority/CA_ID>",                   
                        "aws:SourceAccount": "<ACCOUNT_ID>"               
                        }           
                }       
            },       
            {           
                "Sid": "Allow Access to CRL",           
                "Effect": "Allow",            
                "Principal": "",             
                "Action": "s3:GetObject",             
                "Resource": "<arn:aws:s3:::BUCKET_NAME/crl/CA_ID.crl>",             
                "Condition": {                 
                    "StringEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            },         
            {             
                "Sid": "Access-to-specific-VPCE-only",             
                "Effect": "Deny",             
                "Principal": "",            
                "Action": "s3:GetObject",           
                "Resource": [               
                    "<arn:aws:s3:::BUCKET_NAME>",               
                    "<arn:aws:s3:::BUCKET_NAME>/"             
                ],             
                "Condition": {                 
                    "StringNotEquals": {                     
                        "aws:SourceVpce": "<VPCE_ID>"                 
                        }             
                }         
            }     
        ] 
    }

    Figure 14: S3 bucket CRL properties

    Figure 14: S3 bucket CRL properties

    Create a private hosted zone:

    1. Go to the Route 53 console.
    2. In the left navigation pane, choose Hosted zones.
    3. Choose Create hosted zone.
    4. Configure the following:
      1. Domain name: Enter s3.amazonaws.com
      2. Description: (optional) enter Private hosted zone for S3 CRL endpoint
      3. Type: Select Private hosted zone.
      4. VPC: For Region, select your VPC’s Region; for VPC ID, select your VPC from the dropdown list.
    5. Choose Create hosted zone.

    Create a record set:

    1. Inside your new private hosted zone:
      1. Choose Create record.
      2. Select Simple routing policy.
      3. Choose Next.
    2. Configure record:
      1. Record name: Enter your S3 bucket name.
      2. Record type: Select A – Routes traffic to an IPv4 address.
      3. Alias: Toggle Yes.
      4. Route traffic to: Select Alias to S3 website endpoint.
      5. Region: Select your Region.
      6. S3 endpoint: Select from dropdown list.
      7. TTL: Leave as default (300 seconds).
    3. Choose Create record.
    Figure 15: Hosted zone details

    Figure 15: Hosted zone details

    Verify configuration:

    1. Go to the Amazon EC2 console and choose Launch instance.
    2. Select Amazon Linux 2.
    3. Choose Instance Type.
    4. Select you VPC and subnet.
    5. Under Network settings, select Create security group, then choose Allow SSH traffic from and enter your IP address.
    6. Choose Launch instance.
    7. After the instance is launched, select the instance and choose Connect.
    8. Select EC2 Instance Connect and choose Connect.

    Test the solution

    To test private access from an EC2 instance within your private VPC, verify CRL access using:
    curl -s https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl | openssl crl -text -noout

    If successful, the command completes the following steps, as shown in Figure 16:

    1. Retrieves the CRL from Amazon S3
    2. Decodes it using OpenSSL
    3. Displays comprehensive CRL information including issuer details, update timestamps, revoked certificate list, signature algorithm, and other metadata
    Figure 16: Public access verification

    Figure 16: Public access verification

    To validate your security controls, attempt access from a public EC2 instance using the following command:
    curl https://<bucket-name>.s3.<region>.amazonaws.com/crl/<certificate-id>.crl

    This should fail, receiving an access denied error confirming that the CRL cannot be accessed from the public internet, as shown in Figure 17.

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Figure 17: Access denied error confirming that the CRL cannot be accessed from the public internet

    Conclusion

    In this post, we walked you through two solutions that you can use to make your CRLs accessible to your internal organization, but not publicly available. First, we showed you how to configure a custom CNAME in your CRL distribution point and deploy Lambda functions to automatically copy each newly generated CRL from the default S3 bucket into a private S3 store.

    Next, we showed you a VPC architecture that uses an Amazon S3 VPC gateway endpoint, tightly scoped bucket policies, and private Route 53 DNS zones to make sure that CRL retrieval is confined to your VPC. We also covered the essential IAM and bucket policies that your clients need to access those CRLs securely. You can get started with setting up this solution on AWS Private CA today.

    If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Certificate Manager forum or contact AWS Support.

Rochak Karki

Rochak Karki

Rochak is a Security Specialist Solutions Architect at AWS, focusing on threat detection, incident response, and data protection helping customers build secure environments. Rochak is a US Army veteran and holds a Bachelor of Science in Engineering from the University of Wyoming. Outside of work, he enjoys spending time with family and friends, hiking, and traveling.

Cheryl Wang

Cheryl is an Associate Security Solutions Architect at AWS based in the SF Bay Area. Cheryl is passionate about cybersecurity and helping customers improve their security infrastructure. She holds a B.A. in Computer Science from Wellesley College. Outside of work, she enjoys writing and playing guzheng.

Enhance email security using VPC endpoints with Amazon SES

Post Syndicated from Mamadou Ba original https://aws.amazon.com/blogs/messaging-and-targeting/enhance-email-security-using-vpc-endpoints-with-amazon-ses/

Email’s universal adoption and accessibility make Amazon Simple Email Service (Amazon SES) an ideal platform for delivering critical business communications, such as customer notifications or password resets. However, the ubiquity of email also invites bad actors who seek to actively exploit email’s ubiquity to launch sophisticated attacks. Business email transmissions traverse a complex network with potential vulnerabilities, making email systems prime targets for these malicious actors. Common threats include message interception, email spoofing, unauthorized access to sending services, and service disruption attacks.

Amazon SES handles millions of sensitive communications daily. For example, healthcare providers transmit patient data, financial institutions send transaction alerts, and businesses exchange confidential information. Securing this critical infrastructure requires deep expertise in email systems, threat detection, and advanced security protocols to provide message integrity and confidentiality.

In this post, we discuss and guide you in enhancing your email security by using VPC endpoints with Amazon SES.

Common security challenges customers face sending email with Amazon SES

Consider the challenges faced by a large healthcare provider seeking to send automated appointment reminders and confidential lab results. Although Amazon SES meets their email delivery needs, the IT team must implement strict security measures to satisfy industry, government, and internal requirements. These likely include secure SMTP connections, identity-based access controls, and network isolation to safeguard sensitive patient information.

These common security requirements seek to address two critical concerns. First, they aim to prevent unauthorized access to the organization’s Amazon SES accounts, thereby safeguarding sensitive communications from potential breaches. Second, these measures mitigate the risks of bad actors co-opting their Amazon SES accounts to launch sophisticated email spoofing and phishing attacks.

Either breach could compromise trusted domains, undermining the security of the healthcare provider’s email communications and damaging their reputation.

For organizations with specific network security requirements or compliance mandates, Amazon SES offers VPC endpoint integration to provide additional network-level controls. This approach is particularly valuable for customers who prefer to avoid API calls traversing the public internet or need to ensure email processing workflows remain within private network boundaries.

VPC endpoints create a direct connection between your applications and Amazon SES, offering the following capabilities:

  • Enhanced network isolation: Keeps email traffic within your private network infrastructure
  • Compliance alignment: Supports regulatory frameworks like HIPAA and GDPR that may require additional network controls
  • Network-based access controls: Restricts SES access to authorized IP ranges and subnets
  • Simplified hybrid connectivity: Leverages existing VPN or Direct Connect infrastructure for seamless integration
  • Defense-in-depth architecture: Adds an additional layer of network security to your email infrastructure

Amazon SES VPC endpoints are enabled by AWS PrivateLink for SMTP message traffic. With these VPC endpoints, you can route SMTP email traffic privately within the AWS network between your sending applications, optionally with encryption, and Amazon SES. When using a VPC endpoint, traffic to Amazon SES doesn’t transmit over the internet and never leaves the Amazon network to securely connect your VPC to Amazon SES without availability risks or bandwidth constraints on your network traffic.

At the time of writing, Amazon SES VPC endpoints don’t support API-based email sending (such as SendEmail, SendRawEmail, or SDKs). Amazon SES API traffic should be encrypted and routed using a VPC through a NAT gateway or over the public internet.

Solution overview

Our solution can help you secure your SMTP message traffic by using the following components:

The following diagram illustrates the solution architecture. The architecture assumes you already have connectivity from your on-premises network to your VPC. For instructions to connect your on-premises network to AWS, refer to Hybrid network connections.

For testing purposes, we use connectivity within AWS. The same concept applies if you’re connecting from an on-premises network that is connected to your VPC either through a Virtual Private Network (VPN) or Direct Connect (DX).

The solution workflow consists of the following steps:

  1. Your SMTP sending applications and services are located on premises or in your data center using two subnets:
    1. Subnet A (IP range: 10.10.10.50)
    2. Subnet B (IP range: 10.90.120.50)
  2. Secure connections are transmitted using AWS Direct Connect or VPN connection to a VPC in the same AWS Region as your Amazon SES account.
  3. The SMTP message traffic, optionally encrypted, is sent to the Amazon SES VPC endpoints configured to restrict network connections from the VPC to only specific subnets:
    1. Traffic on approved subnet A (10.10.10.50) is sent to Amazon SES.
    2. Traffic on denied subnet B (10.90.120.50) is dropped (not sent to Amazon SES).
  4. SMTP traffic from only the allowed subnet A is further restricted to an IAM policy with valid SMTP credentials.
  5. Messages that conform to the traffic and authentication policies are passed to Amazon SES for final delivery to recipients.

Prerequisites

To implement this solution, you must have the following prerequisites:

  • Amazon SES, configured with at least one verified identity, in the same Region as the VPC.
  • An existing VPC in the same Region as Amazon SES. This can be the default VPC. For more information, see Plan your VPC.
  • An SMTP sending application (optionally supporting TLS encryption) located in one of the following options:
    • On premises or in a data center that is connected to the VPC through a private network connection (such as Direct Connect or VPN). For more details about private network connections to AWS, refer to Network-to-Amazon VPC connectivity options.
    • In the VPC running on a compute resource such as Amazon Elastic Compute Cloud (Amazon EC2) or AWS Lambda. For this post, we use an EC2 instance in the VPC and connect to Amazon SES through the VPC endpoint on port 587 with TLS enabled. Note that AWS blocks outbound SMTP traffic on port 25 across most AWS services. Use an alternative TCP port, such as 465, 587, 2465, or 2587. Request port 25 exemption by submitting a request to AWS Support from your AWS account using the “Request to remove email sending limitations” form. This can take upwards of 7 business days to be reviewed; approval is not guaranteed. Amazon SES uses an opportunistic TLS policy by default for encrypting messages when the receiving host supports it. You should use encryption whenever it is available.
  • For testing, you can use one of the following options:
  • DNS resolution for resources in the VPC with the Amazon SES VPC endpoints in the source network. To learn more, see Resolving DNS queries between VPCs and your network.

Create security group

The first step is to create a security group with inbound rules that only allow a specific IP range on the appropriate port (host-permitting, 25, 465, 587, 2465, or 2587). In our example, we only allow subnet A (IP range: 10.10.10.50) on port 587. Complete the following steps to create the security group:

  1. In the navigation pane of the Amazon EC2 console, under Network & Security, choose Security groups.
  2. Choose Create security group.
  3. For Security group name, enter a unique name that identifies the security group (we use ses-vpce-sec-group).
  4. For Description, enter the purpose of the security group.
  5. For VPC, choose the VPC in which you will host the application that will use Amazon SES.
  6. Under Inbound rules, choose Add rule.
  7. For Type, choose Custom TCP.
  8. For Port range, enter the port number that you want to use to send email. You can choose from 465, 587, 2465, or 2587. For this post, we use 587.
  9. For Source type, choose Custom.
  10. Enter the private IP CIDR range for subnet A (IP range: 10.10.10.50), which contains the resources that will use the VPC endpoint to communicate with Amazon SES.
  11. Choose Create security group.

Create VPC endpoint to connect the VPC to Amazon SES

Complete the following steps to create your VPC endpoint:

  1. On the Amazon VPC console, in the navigation pane, under PrivateLink and Lattice, choose Endpoints.
  2. Choose Create endpoint.
  3. Optionally, under Endpoint settings, create a tag in the Name tag field.
  4. For Service category, select AWS services.
  5. For Services, filter for and select smtp.
  6. For VPC, choose a VPC (for more details, see Prerequisites).
  7. For Subnets, select Availability Zones and Subnet IDs.
    Amazon SES doesn’t support VPC endpoints in the following Availability Zones: use1-az2, use1-az3, use1-az5, usw1-az2, usw2-az4, apne2-az4, cac1-az3, and cac1-az4.
  1. For Security groups, choose the security group you created earlier.
  2. Optionally, for Tags, create one or more tags.
  3. Choose Create endpoint.
    Wait approximately 5 minutes while Amazon VPC creates the endpoint. When the endpoint is ready to use, the value in the Status column changes to Available.
  4. Copy the VPC endpoint ID to your clipboard to use in the next step.

Optionally, you can test the connection to make sure the VPC endpoint is configured properly by using command line tools to send a test email using the Amazon SES SMTP interface from an EC2 instance in the same VPC where you just created the email-smtp VPC endpoint. For more information, see Using the Amazon SES SMTP interface to send email.

Create SMTP credentials in Amazon SES that will be used by sender applications to authenticate

Complete the following steps to create SMTP credentials:

  1. On the Amazon SES console, choose SMTP Settings in the navigation pane.
  2. Choose Create SMTP credentials.
  3. Enter your preferred user name and choose Create user.
  4. Download the user’s SMTP credentials or copy the credentials to AWS Secrets Manager. (we will use these SMTP credentials in the next step).
  5. Return to the SES console.

Limit traffic to the Amazon SES VPC endpoint using IAM

In this step, we limit traffic to the Amazon SES VPC endpoint using an IAM policy. The IAM policy has a condition that restricts access to aws:SourceVpce. Complete the following steps:

  1. On the Amazon SES console, choose SMTP Settings in the navigation pane.
  2. Choose Manage my existing SMTP credentials.
  3. Choose the user you created earlier, then choose Permissions.
  4. Choose the policy name AmazonSesSendingAccess to go to the IAM policy editor.
  5. Replace the policy content in JSON view with the following policy, which adds the conditions for traffic to come from the Amazon SES VPC endpoint:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "SESSendPermissions",
      "Effect": "Allow",
      "Action": [
        "ses:SendEmail",
        "ses:SendCustomVerificationEmail",
        "ses:SendRawEmail",
        "ses:SendBulkEmail"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "aws:SourceVpce": ""
        }
      }
    }
  ]
}
  1. Choose Next.
  2. Choose Save changes.

As a best practice, rotate your SMTP credentials on a periodic basis and whenever there is concern over the confidentiality of the credentials. For more information, see Automate the Creation & Rotation of Amazon Simple Email Service SMTP Credentials.

Test permissions and connectivity

To test permissions and connectivity by sending a test email, complete the following steps to create an EC2 instance in your VPC:

  1. On the Amazon EC2 console, create a new EC2 instance.
  2. Make sure to specify your VPC and subnet. The subnet must be the same as the one selected in previous steps.
  3. Use the SMTP script in the Amazon SES documentation for testing.

This screenshot shows the test result using the SMTP VPC Endpoint URL.

This configuration allows Amazon SES to only accept SMTP message traffic from applications from allowed on-premises subnets with connectivity to AWS and in the VPC that originates from the permitted SMTP IAM identity policy. This design follows the AWS least privilege access approach to security. To learn more, refer to Strategies for achieving least privilege at scale.

Clean up

After testing, if you don’t want to keep these configurations you should delete the EC2 instance, the VPC endpoint, the SMTP credential, and the IAM user.

Conclusion

In this post, we demonstrated how to implement a secure Amazon SES environment by combining multiple AWS security controls. By using Amazon SES VPC endpoints, security groups, and IAM policies, you can create a robust security architecture that restricts email sending capabilities to authorized networks only.

This multi-layered approach addresses critical security challenges by avoiding public internet exposure for SMTP traffic, enabling comprehensive traffic monitoring through VPC flow logs, and establishing defined network boundaries that satisfy strict compliance requirements.

The solution provides significant security benefits while maintaining the scalability and reliability that Amazon SES customers expect. Organizations can effectively protect sensitive email communications, prevent unauthorized access, and maintain compliance with industry regulations like HIPAA and GDPR. This becomes increasingly important as email-based threats continue to evolve and regulatory requirements become more stringent.

Start implementing these security controls today:

  • Deploy this solution in your development environment first, testing each component thoroughly
  • Review the security best practices for Amazon SES and VPC endpoints
  • Validate your implementation against your organization’s security requirements
  • Create a detailed migration plan for your production environment
  • Monitor and audit your email infrastructure regularly using VPC Flow Logs and Amazon CloudWatch

For additional guidance, consult the Amazon SES documentation, explore the AWS Security Blog for related articles, or engage with AWS Support. Remember to periodically review and update your security configurations as new features and best practices emerge.


About the authors

AWS Transfer Family SFTP connectors now support VPC-based connectivity

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-transfer-family-sftp-connectors-now-support-vpc-based-connectivity/

Many organizations rely on the Secure File Transfer Protocol (SFTP) as the industry standard for exchanging critical business data. Traditionally, securely connecting to private SFTP servers required custom infrastructure, manual scripting, or exposing endpoints to the public internet.

Today, AWS Transfer Family SFTP connectors now support connectivity to remote SFTP servers through Amazon Virtual Private Cloud (Amazon VPC) environments. You can transfer files between Amazon Simple Storage Service (Amazon S3) and private or public SFTP servers while applying the security controls and network configurations already defined in your VPC. This capability helps you integrate data sources across on-premises environments, partner-hosted private servers, or internet-facing endpoints, with the operational simplicity of a fully managed Amazon Web Services (AWS) service.

New capabilities with SFTP connectors
The following are the key enhancements:

  • Connect to private SFTP servers – SFTP connectors can now reach endpoints that are only accessible within your AWS VPC connection. These include servers hosted in your VPC or a shared VPC, on-premises systems connected over AWS Direct Connect, and partner-hosted servers connected through VPN tunnels.
  • Security and compliance – All file transfers are routed through the security controls already applied in your VPC, such as AWS Network Firewall or centralized ingress and egress inspection. Private SFTP servers remain private and don’t need to be exposed to the internet. You can also present static Elastic IP or bring your own IP (BYOIP) addresses to meet partner allowlist requirements.
  • Performance and simplicity – By using your own network resources such as NAT gateways, AWS Direct Connect or VPN connections, connectors can take advantage of higher bandwidth capacity for large-scale transfers. You can configure connectors in minutes through the AWS Management Console,  AWS Command Line Interface (AWS CLI), or AWS SDKs without building custom scripts or third-party tools.

How VPC- based SFTP connections work
SFTP connectors use Amazon VPC Lattice resources to establish secure connectivity through your VPC. Key constructs include a resource configuration and a resource gateway. The resource configuration represents the target SFTP server, which you specify using a private IP address or public DNS name. The resource gateway provides SFTP connector access to these configurations, enabling file transfers to flow through your VPC and its security controls.

The following architecture diagram illustrates how traffic flows between Amazon S3 and remote SFTP servers. As shown in the architecture, traffic flows from Amazon S3 through the SFTP connector into your VPC. A resource gateway is the entry point that handles inbound connections from the connector to your VPC resources. Outbound traffic is routed through your configured egress path, using Amazon VPC NAT gateways with Elastic IPs for public servers or AWS Direct Connect and VPN connections for private servers. You can use existing IP addresses from your VPC CIDR range, simplifying partner server allowlists. Centralized firewalls in the VPC enforce security policies, and customer-owned NAT gateways provide higher bandwidth for large-scale transfers.

When to use this feature
With this capability, developers and IT administrators can simplify workflows while meeting security and compliance requirements across a range of scenarios:

  • Hybrid environments – Transfer files between Amazon S3 and on-premises SFTP servers using AWS Direct Connect or AWS Site-to-Site VPN, without exposing endpoints to the internet.
  • Partner integrations – Connect with business partners’ SFTP servers that are only accessible through private VPN tunnels or shared VPCs. This avoids building custom scripts or managing third-party tools, reducing operational complexity.
  • Regulated industries – Route file transfers through centralized firewalls and inspection points in VPCs to comply with financial services, government, or healthcare security requirements.
  • High-throughput transfers – Use your own network configurations such as NAT gateways, AWS Direct Connect, or VPN connections with Elastic IP or BYOIP to handle large-scale, high-bandwidth transfers while retaining IP addresses already on partner allowlists.
  • Unified file transfer solution – Standardize on Transfer Family for both internal and external SFTP connectivity, reducing fragmentation across file transfer tools.

Start building with SFTP connectors
To begin transferring files with SFTP connectors through my VPC environment, I follow these steps:

First, I configure my VPC Lattice resources. In the Amazon VPC console, under PrivateLink and Lattice in the navigation pane, I choose Resource gateways, choose Create resource gateway to create one to act as the ingress point into my VPC. Next, under PrivateLink and Lattice in the navigation pane, I choose Resource configuration and choose Create resource configuration to create a resource configuration for my target SFTP server. Specify the private IP address or public DNS name, and the port (typically 22).

Then, I configure AWS Identity and Access Management (IAM) permissions. I ensure that the IAM role used for connector creation has transfer:* permissions, and VPC Lattice permissions (vpc-lattice:CreateServiceNetworkResourceAssociation, vpc-lattice:GetResourceConfiguration, vpc-lattice:AssociateViaAWSService). I update the trust policy on the IAM role to specify transfer.amazonaws.com as a trusted principal. This enables AWS Transfer Family to assume the role when creating and managing my SFTP connectors.

After that, I create an SFTP connector through the AWS Transfer Family console. I choose SFTP Connectors and then choose Create SFTP connector. In the Connector configuration section, I select VPC Lattice as the egress type, then provide the Amazon Resource Name (ARN) of the Resource Configuration, Access role, and Connector credentials. Optionally, include a trusted host key for enhanced security, or override the default port if my SFTP server uses a nonstandard port.

Next, I test the connection. On the Actions menu, I choose Test connection to confirm that the connector can reach the target SFTP server.

Finally, after the connector status is ACTIVE, I can begin file operations with my remote SFTP server programmatically by calling Transfer Family APIs such as StartDirectoryListing, StartFileTransfer, StartRemoteDelete, or StartRemoteMove. All traffic is routed through my VPC using my configured resources such as NAT gateways, AWS Direct Connect, or VPN connections together with my IP addresses and security controls.

For the complete set of options and advanced workflows, refer to the AWS Transfer Family documentation.
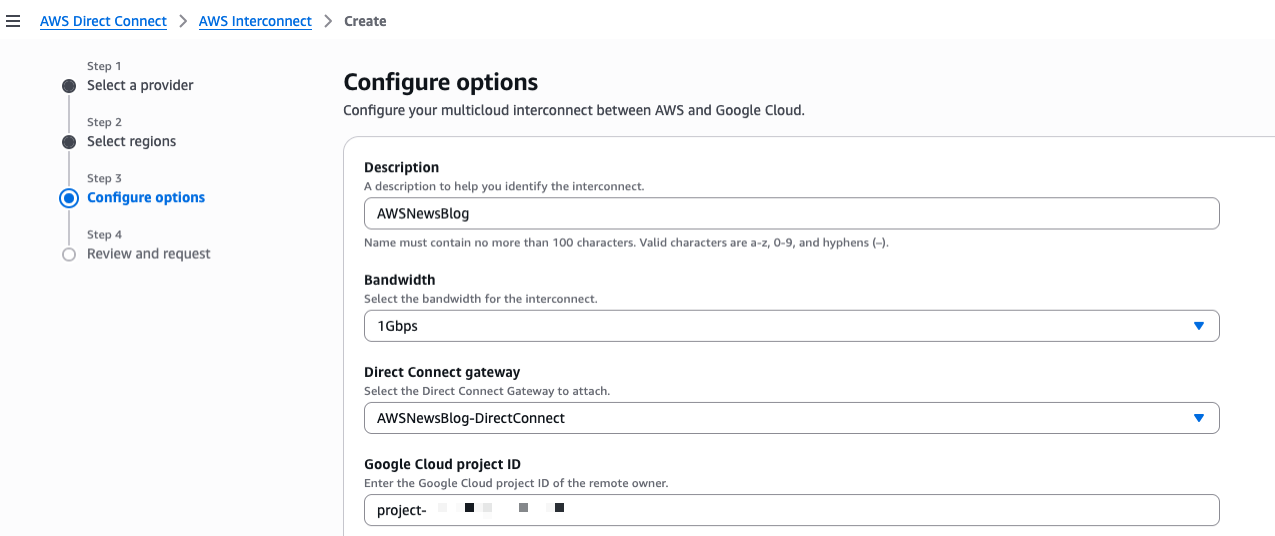
Now available

SFTP connectors with VPC-based connectivity are now available in 21 AWS Regions. Check the AWS Services by Region for the latest supported AWS Regions. You can now securely connect AWS Transfer Family SFTP connectors to private, on-premises, or internet-facing servers using your own VPC resources such as NAT gateways, Elastic IPs, and network firewalls.

Betty

AWS Weekly Roundup: Amazon Q Developer, AWS Step Functions, AWS Cloud Club Captain deadline, and more (September 22, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-q-developer-aws-step-functions-aws-cloud-club-captain-deadline-and-more-september-22-2025/

Three weeks ago, I published a post about the new AWS Region in New Zealand (ap-southeast-6). This led to an incredible opportunity to visit New Zealand, where I met passionate builders and presented at several events including Serverless and Platform Engineering meetup, AWS Tools and Programming meetup, AWS Cloud Clubs in Auckland, and AWS Community Day New Zealand.

During my content creation process for these presentations, I discovered a useful feature in Amazon Q CLI called tangent mode. This feature has transformed how I stay focused by creating conversation checkpoints that let you explore side topics without losing your main thread.

This feature is in experimental mode, and you can enable it with q settings chat.enableTangentMode true. Try it out and see if it helps you.

Last week’s launches
Here are some launches that got my attention:

  • New Foundation Models in Amazon Bedrock — Amazon Bedrock expands its model selection with Qwen model family, DeepSeek-V3.1, and Stability AI image services now generally available, giving developers access to powerful multilingual models and advanced image generation capabilities for text generation, code generation, image creation, and complex problem-solving tasks.
  • Amazon VPC Reachability Analyzer Expands to Seven New Regions — Network Access Analyzer capabilities are now available in additional regions, helping customers analyze and troubleshoot network connectivity issues across their VPC infrastructure with improved global coverage.
  • Amazon Q Developer Supports Remote MCP Servers — Amazon Q Developer now integrates with remote Model Context Protocol (MCP) servers, enabling developers to extend their AI assistant capabilities with custom tools and data sources for enhanced development workflows.
  • AWS Step Functions Enhances Distributed Map with New Data Source Options — Step Functions introduces additional data source options and improved observability features for Distributed Map, making it easier to process large-scale parallel workloads with better monitoring and debugging capabilities.
  • Amazon Corretto 25 Generally Available — Amazon’s no-cost, multiplatform distribution of OpenJDK 25 is now generally available, providing Java developers with long-term support, performance enhancements, and security updates for building modern applications.
  • Amazon SageMaker HyperPod Introduces Autoscaling — SageMaker HyperPod now supports automatic scaling capabilities, allowing machine learning teams to dynamically adjust compute resources based on workload demands, optimizing both performance and cost for distributed training jobs.

Additional Updates

  • AWS Named Leader in 2025 Gartner Magic Quadrant for AI Code Assistants – AWS has been recognized as a Leader in Gartner’s Magic Quadrant for AI Code Assistants, highlighting Amazon Q Developer’s capabilities in helping developers write code faster and more securely with AI-powered suggestions.
  • Become an AWS Cloud Club Captain – Only a couple of days before it closes! Join a growing network of student cloud enthusiasts by becoming an AWS Cloud Club Captain! As a Captain, you’ll get to organize events and build cloud communities while developing leadership skills. The application window is open September 1-28, 2025.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events as well as AWS re:Invent and AWS Summits:

  • AWS AI Agent Global Hackathon – This is your chance to dive deep into our powerful generative AI stack and create something truly awesome. From September 8th to October 20th, you have the opportunity to create AI agents using AWS suite of AI services, competing for over $45,000 in prizes and exclusive go-to-market opportunities.
  • AWS Gen AI Lofts – You can learn AWS AI products and services with exclusive sessions and meet industry-leading experts, and have valuable networking opportunities with investors and peers. Register in your nearest city: Mexico City (September 30–October 2), Paris (October 7–21), London (Oct 13–21), and Tel Aviv (November 11–19).
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: South Africa (September 20), Bolivia (September 20), Portugal (September 27), and Manila (October 4-5).

You can browse all upcoming AWS events and AWS startup events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Happy building!

— Donnie

Amazon Bedrock baseline architecture in an AWS landing zone

Post Syndicated from Abdel-Rahman Awad original https://aws.amazon.com/blogs/architecture/amazon-bedrock-baseline-architecture-in-an-aws-landing-zone/

As organizations increasingly adopt Amazon Bedrock to build and deploy large-scale AI applications, it’s important that they understand and adopt critical network access controls to protect their data and workloads. These generative AI-enabled applications might have access to sensitive or confidential information within their knowledge bases, Retrieval Augmented Generation (RAG) data sources, or models themselves, which could pose a risk if exposed to unauthorized parties. Additionally, organizations might want to limit access to certain AI models to specific teams or services, making sure only authorized users can use the most powerful capabilities. Another important consideration is cost optimization, because organizations need to be able to monitor and control access to manage various aspects of their cloud spending.

In this post, we explore the Amazon Bedrock baseline architecture and how you can secure and control network access to your various Amazon Bedrock capabilities within AWS network services and tools. We discuss key design considerations, such as using Amazon VPC Lattice auth policies, Amazon Virtual Private Cloud (Amazon VPC) endpoints, and AWS Identity and Access Management (IAM) to restrict and monitor access to your Amazon Bedrock capabilities.

By the end of this post, you will have a better understanding of how to configure your AWS landing zone to establish secure and controlled network connectivity to Amazon Bedrock across your organization using VPC Lattice.

Solution overview

Addressing the aforementioned challenges requires a well-designed network architecture and security controls. For this, we use the standard AWS Landing Zone Accelerator networking configuration. It provides a good starting point for managing network communication across multiple accounts. On top of the AWS Landing Zone Accelerator network design, we add two shared accounts.

In this solution design, we create a centralized architecture for managing organization AI capabilities across different accounts. The architecture consists of three main parts that work together to provide secure and controlled access to AI services:

  • Service network account – This account serves as the central networking hub for the organization, managing network connectivity and access policies. Through this account, network administrators can centrally manage and control access to AI services across the organization. The account follows AWS Landing Zone Accelerator networking practices that scale with enterprise organizational needs.
  • Generative AI account – This account hosts the organization’s Amazon Bedrock capabilities and serves as the central point for AI/ML management. The organization’s AI/ML scientists and prompt engineers will centrally build and manage Amazon Bedrock capabilities. The account provides access to various large language models (LLMs) through Amazon Bedrock by using VPC interface endpoints, while also enabling centralized monitoring of cost consumption and access patterns.
  • Workload accounts (dev, test, prod) – These accounts represent different environments where teams develop and deploy applications that consume AI services. Through secure network connections established through the service network account, these workload accounts can access the AI capabilities hosted in the generative AI account. This separation enforces proper isolation between development, testing, and production workloads while maintaining secure access to AI services.
Amazon Bedrock baseline architecture in an AWS landing zone

Amazon Bedrock baseline architecture in an AWS landing zone

The following diagram illustrates the solution architecture.

The service network account has its own VPC Lattice service network—a centralized networking construct that enables service-to-service communication across your organization, which is shared with workload accounts using AWS Resource Access Manager (AWS RAM) to enable VPC Lattice Service network sharing.

Workload accounts (dev, test, prod) establish VPC associations with the shared VPC Lattice service network by creating a service network association in their VPC. When an application in these accounts makes a request, it first queries the VPC resolver for DNS resolution. The resolver routes the traffic to the VPC Lattice service network.

Access control is implemented through an VPC Lattice auth policy. The service network policies determine which accounts can access the VPC Lattice service network, and service-level policies control access to specific AI services and define what actions each account can perform.

In the central AI services account, we find the proxy layer, we create a VPC Lattice service that points to a proxy layer, which acts as a single entry point, providing workload accounts access to Amazon Bedrock. This proxy layer then connects to Amazon Bedrock through VPC endpoints. Through this setup, the AI team can configure which foundation models (FMs) are available and manage access permissions for different workload accounts. After the necessary policies and connections are in place, workload accounts can access Amazon Bedrock capabilities through the established secure pathway. This setup enables secure, cross-account access to AI services while maintaining centralized control and monitoring.

Network components

We use VPC Lattice, which is a fully managed application networking service that helps you simplify network connectivity, security, and monitoring for service-to-service communication needs. With VPC Lattice, organizations can achieve a centralized connectivity pattern to control and monitor access to the services required for building generative AI applications.

For details about VPC Lattice, refer to the Amazon VPC Lattice User Guide. The following is an overview of the constructs you can use in setting up the centralized pattern in this solution:

  • VPC Lattice service network – You can use the VPC Lattice service network to provide central connectivity and security to the central AI services account. The service network is a logical grouping mechanism that simplifies how you can enable connectivity across VPCs or accounts, and apply common security policies for application communication patterns. You can create a service network in an account and share it with other accounts within or outside AWS Organizations using AWS RAM.
  • VPC Lattice service – In a service network, you can associate a VPC Lattice service, which consists of a listener (protocol and port number), routing rules that allow for control of the application flow (for example, path, method, header-based, or weighted routing), and target group, which defines the application infrastructure. A service can have multiple listeners to meet various client capabilities. Supported protocols include HTTP, HTTPS, gRPC, and TLS. The path-based routing allows control to various high-performing FMs and other capabilities you would need to build a generative AI application.
  • Proxy layer – You use a proxy layer for the VPC Lattice service target group. The proxy layer can be built based on your organization’s preference of AWS services, such as AWS Lambda, AWS Fargate, or Amazon Elastic Kubernetes Service (Amazon EKS). The purpose of the proxy layer is to provide a single entry point to access LLMs, knowledge bases, and other capabilities that are tested and approved according to your organization’s compliance requirements.
  • VPC Lattice auth policies – For security, you use VPC Lattice auth policies. VPC Lattice auth policies are specified using the same syntax as IAM policies. You can apply an auth policy to VPC Lattice service network as well as to the VPC Lattice service.
  • Fully Qualified Domain Names –To facilitate service discovery, VPC Lattice supports custom domain names for your services and resources, and maintains a Fully Qualified Domain Name (FQDN) for each VPC Lattice service and resource you define. You can use these FQDNs in your Amazon Route 53 private hosted zone configurations, and empower business units or teams to discover and access services and resources.
  • Service network VPC – Business units or teams can access generative AI services in a service network using service network VPC associations or a service network VPC endpoint.
  • Monitoring – You can choose to enable monitoring at the VPC Lattice service network level and VPC Lattice service level. VPC Lattice generates metrics and logs for requests and responses, making it more efficient to monitor and troubleshoot applications

The preceding guidance takes a “secure by default” approach—you must be explicit about which features, models, and so on should be accessed by which business unit. The setup also enables you to implement a defense-in-depth strategy at multiple layers of the network:

  • The first level of defense is that business team needs to connect to the service network in order to get access to the generative AI service through the central AI service account.
  • The second level includes network-level security protections in the business team’s VPC for the service network, such as security groups and network access control lists (ACLs). By using these, you can allow access to specific workloads or teams in a VPC.
  • The third level is through the VPC Lattice auth policy, which you can apply at two layers: at the service network level to allow authenticated requests within the organization, and at the service level to allow access to specific models and features.

VPC Lattice auth policy

This solution makes it possible to centrally manage access to Amazon Bedrock resources across your organization. This approach uses an VPC Lattice auth policy to centrally control Amazon Bedrock resources and manage it from one location across all the organization accounts.

Typically, the auth policy on the service network is operated by the network or cloud administrator. For example, allowing only authenticated requests from specific workloads or teams in your AWS organization. In the following example, access is granted to invoke the generated AI service for authenticated requests and to principals that are part of the o-123456example organization:

{
   "Version": "2012-10-17",
   "Statement": [
      {
         "Effect": "Allow",
         "Principal": "*",
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": "*",
         "Condition": {
            "StringEquals": {
               "aws:PrincipalOrgID": [ 
                  "o-123456example"
               ]
            }
         }
      }
   ]
}

The auth policy at the service level is managed by the central AI service team to set fine-grained controls, which can be more restrictive than the coarse-grained authorization applied at the service network level. For example, the following policy restricts access to claude-3-haiku for only business-team1:

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Effect": "Allow",
         "Principal": {
            "AWS": [
               "arn:aws:iam::<account-number>:role/businss-team1"
            ]
         },
         "Action": "vpc-lattice-svcs:Invoke",
         "Resource": [
            "arn:aws:vpc-lattice:<aws-region>:<account-number>:service/svc-0123456789abcdef0/*"
         ],
         "Condition": {
            "StringEquals": {
               "vpc-lattice-svcs:RequestQueryString/modelid": "claude-3-haiku"            }
         }
      }
   ]
}

Monitoring and tracking

This design employs three monitoring approaches, using Amazon CloudWatch, AWS CloudTrail, and VPC Lattice access logs. This strategy provides a view of service usage, security, and performance.

CloudWatch metrics offer real-time monitoring of VPC Lattice service performance and usage. CloudWatch tracks metrics such as request counts and response times for Amazon Bedrock related endpoints, allowing for the setup of alarms for proactive management of service health and capacity. This enables monitoring of overall usage patterns of Amazon Bedrock models across different business units, facilitating capacity planning and resource allocation. CloudTrail provides detailed API-level auditing of Amazon Bedrock related actions. It logs cross-account access attempts and interactions with Amazon Bedrock services, providing a compliance and security audit trail. This tracking of who is accessing which Amazon Bedrock models, when, and from which accounts helps organizations adhere to their organizational policies.VPC Lattice access logs provide detailed insights into HTTP/HTTPS requests to Amazon Bedrock services, capturing specific usage patterns of AI models by different business teams. These logs contain client-specific information, which for example can be used to enable organizations to implement capabilities such as charge-back models. This allows for accurate attribution of AI service usage to specific teams or departments, facilitating fair cost allocation and responsible resource utilization across the organization. These services work together to enhance security, optimize performance, and provide valuable insights for managing cross-account Amazon Bedrock access.

Conclusion

In this post, we explored the importance of securing and controlling network access to Amazon Bedrock capabilities within an organization’s AWS landing zone. We discussed the key business challenges, such as the need to protect sensitive information in Amazon Bedrock knowledge bases, limit access to AI models, and optimize cloud costs by monitoring and controlling Amazon Bedrock capabilities. To address these challenges, we outlined a multi-layered network solution that uses AWS networking services, including a VPC Lattice auth policy to restrict and monitor access to Amazon Bedrock capabilities. Try out this solution for your own use case, and share your feedback in the comments.


About the authors

Build a multi-Region analytics solution with Amazon Redshift, Amazon S3, and Amazon QuickSight

Post Syndicated from Donatas Kuchalskis original https://aws.amazon.com/blogs/big-data/build-a-multi-region-analytics-solution-with-amazon-redshift-amazon-s3-and-amazon-quicksight/

Organizations increasingly face complex requirements balancing regional data sovereignty with global analytics needs. Regulatory frameworks like GDPR, HIPAA, and local data protection laws often mandate storing data in specific geographic regions, and business operations require global teams to access and analyze this data efficiently.

This post explores how to effectively architect a solution that addresses this specific challenge: enabling comprehensive analytics capabilities for global teams while making sure that your data remains in the AWS Regions required by your compliance framework. We use a variety of AWS services, including Amazon Redshift, Amazon Simple Storage Service (Amazon S3), and Amazon QuickSight.

It’s important to note that this solution focuses primarily on data residency (where data is stored) and not on preventing data from being in transit between Regions. Organizations with strict data transit restrictions might need additional controls beyond what’s covered here. We show how you can configure AWS across Regions to help meet business needs and regulatory requirements simultaneously.

Cross-Region architecture requirements

Before implementing a cross-Region solution, it’s important to understand when this approach is actually necessary. Although single-Region deployments offer simplicity and cost advantages, several specific business and regulatory scenarios warrant a cross-Region approach:

  • Data sovereignty and residency requirements – When regulations like GDPR, HIPAA, or local data sovereignty laws require data to remain in specific geographic boundaries while still enabling global analytics capabilities
  • Global operations with local compliance – When your organization operates globally, but needs to adhere to regional compliance frameworks while maintaining unified analytics
  • Performance optimization for global users – When your organization needs to optimize analytics performance for users in different geographic areas while centralizing data governance
  • Enhanced business continuity – When your analytics capabilities need higher availability and Regional redundancy to support mission-critical business processes

Use case: Financial services analytics with Regional data residency

Consider a financial services company with the following business and regulatory requirements:

  • Data residency requirement – All customer financial data must remain in the Bahrain Region (me-south-1) to comply with local financial regulations.
  • Global analytics capability – The organization’s data science team operates from European offices and needs to access and analyze the financial data without moving it out of its mandated storage Region.
  • Advanced analytics requirements – Business leaders need interactive data exploration and natural language query capabilities to derive insights from financial data.
  • Performance requirement – Specific dashboard queries require subsecond response times for both local executives and the global management team.

This specific combination of requirements can’t be met with a single-Region deployment. Let’s explore how to architect a solution.

Solution overview

The following architecture is designed to address the specific challenge of using QuickSight in one Region while maintaining data in another Region.

As shown in the architecture diagram, data engineers based in Bahrain (me-south-1) work with local data, whereas data engineers in Stockholm (eu-north-1) and analysts in Ireland (eu-west-1) can securely access the same data through Redshift datashares and virtual private cloud (VPC) peering connections. This approach maintains data residency in me-south-1 while enabling global access.

The solution consists of the following key components:

  • Primary data Region (me-south-1):
    • Redshift cluster (primary data repository)
    • S3 buckets for data lake storage
    • Private and public subnets with appropriate security controls
    • Data must remain in this Region for compliance reasons
  • Analytics services Region (eu-west-1):
    • QuickSight deployment
    • Cross-Region VPC peering connection to the primary Region
    • Data access using Redshift datashares (no data replication)
  • Data engineering Region (eu-north-1):
    • Redshift consumer cluster for data engineering workloads
    • Data access using Redshift datashares from me-south-1
    • Makes it possible for data engineering teams in eu-north-1 to access and work with data while maintaining compliance

Before implementing this architecture, evaluate whether:

  • Your requirements actually necessitate a cross-Region approach
  • The performance impact is acceptable for your use case
  • The additional cost is justified by your business requirements

For most analytics workloads, a single-Region architecture remains the recommended approach for simplicity, performance, and cost-effectiveness. Consider cross-Region architectures only when specific business and compliance requirements make them necessary.

Establish cross-Region network connectivity: Amazon Redshift to QuickSight

The foundation of a cross-Region solution is secure, reliable network connectivity. VPC peering provides a straightforward approach for connecting VPCs across Regions. To implement VPC peering in Amazon Virtual Private Cloud (Amazon VPC), complete the following steps:

  1. Create a new VPC in the secondary Region (eu-west-1):
    1. Open the Amazon VPC console in the eu-west-1 Region.
    2. Choose Create VPC.
    3. Set IPv4 CIDR block to 172.32.0.0/16 (verify there is no overlap with the primary Region VPC).
    4. Select Auto-generate to create subnets automatically within this new VPC.
    5. Leave other settings as default and choose Create VPC.

  1. Set up VPC peering:
    1. On the Amazon VPC console, choose Peering connections in the navigation pane and choose Create peering connection.
    2. Select the new eu-west-1 VPC as the requester.
    3. For Select another VPC to peer with, select My account and Another Region.
    4. Choose the primary Region (me-south-1) and enter the VPC ID.
    5. Choose Create peering connection.

  1. Accept the VPC peering connection:
    1. Switch to the primary Region on the Amazon VPC console.
    2. Choose Peering connections in the navigation pane and select the pending connection.
    3. On the Actions dropdown menu, choose Accept request.

  1. Update the route tables:
    1. On the  secondary Region Amazon VPC console, choose Route tables in the navigation pane.
    2. Choose the route table for the new VPC.
    3. Choose Edit routes and add a new route:
      • Destination: Primary Region VPC CIDR (e.g., 172.31.0.0/16).
      • Target: Choose the peering connection.
    4. On the primary Region Amazon VPC console, repeat the process, adding a route to the secondary Region VPC CIDR (172.32.0.0/16) using the peering connection.

  1. Configure security groups:
    1. On the secondary Region Amazon VPC console, choose Security groups in the navigation pane and create a new security group.
    2. Add an outbound rule:
      • Type: Custom TCP
      • Port range: 5439
      • Destination: Primary Region VPC CIDR

    3. On the primary Region Amazon VPC console, locate the Redshift cluster’s security group.
    4. Add an inbound rule:
      • Type: Custom TCP
      • Port range: 5439
      • Source: Secondary Region VPC CIDR

  1. Configure DNS settings:
    1. On the Amazon VPC console for both Regions, choose Your VPCs in the navigation pane.
    2. Select each VPC, and on the Actions dropdown menu, choose Edit DNS hostnames.
    3. Select Enable DNS resolution and Enable DNS hostnames.

Implement cross-Region data sharing

Rather than replicating data, which could create compliance issues, you can use Redshift datashares to provide secure, read-only access to data across Regions. Complete the following steps to set up your datashares:

  1. Create producer datashares in the primary Region:
    1. On the Amazon Redshift console, choose Query editor v2 in the navigation pane to connect to your primary Region Redshift cluster (me-south-1).
    2. Run the following commands:
      -- In Primary Region Redshift
      
      CREATE DATASHARE datashare_1;
      ALTER DATASHARE datashare_1 ADD SCHEMA analytics;
      ALTER DATASHARE datashare_1 ADD TABLE analytics.customers;
      ALTER DATASHARE datashare_1 ADD TABLE analytics.transactions;
      
      -- Grant usage permissions
      	
      GRANT USAGE ON DATASHARE datashare_1 TO ACCOUNT '123456789012';

  1. Create a consumer database in the secondary Region:
  2. Connect to your secondary Region Redshift cluster (eu-west-1) using the query editor and run the following commands:
    -- In Secondary Region Redshift
    
    CREATE DATABASE consumer_db FROM DATASHARE datashare_1 OF ACCOUNT '123456789012'REGION 'me-south-1';
  3. Verify the datashare configuration with the following code:
    -- In Secondary Region Redshift
    
    SELECT * FROM SVV_DATASHARE_CONSUMERS;
    SELECT * FROM SVV_DATASHARE_OBJECTS; 

This approach maintains data residency in the primary Region while enabling analytics access from another Region, addressing the core challenge of Regional service limitations. For our financial services company example, this makes sure that customer financial data remains in Bahrain (me-south-1) while making it securely accessible to the data science team in Europe (eu-west-1).

Configure QuickSight in the analytics Region

With network connectivity and data sharing established, complete the following steps to configure QuickSight to securely access the Redshift data:

  1. Set up a QuickSight VPC connection:
    1. Open the QuickSight console in the secondary Region.
    2. Choose Manage QuickSight, VPC connections, and Add VPC connection.
    3. Configure the connection:
      • Name: Enter a name (for example, Cross-Region-Connection).
      • VPC: Choose the secondary Region VPC.
      • Subnet: Choose the automatically created subnets.
      • Security group: Choose the security group created for cross-Region access.

  1. Add a QuickSight IP range to the data source security group:
    1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console in the primary Region.
    2. Choose Security groups in the navigation pane and find the security group for your data source.
    3. Edit the inbound rules.
    4. Add a new rule:
      • Type: HTTPS (443)
      • Protocol: TCP
      • Port range: 443
      • Source: QuickSight IP range for the secondary Region (for example, 52.210.255.224/27 for eu-west-1).

QuickSight IP ranges can change over time. Refer to AWS Regions, websites, IP address ranges, and endpoints for current IP ranges.

  1. Create a QuickSight data source:
    1. On the QuickSight console, choose Datasets in the navigation pane.
    2. Choose New dataset, then choose Redshift.
    3. Configure the connection:
      • Data source name: Enter a descriptive name.
      • Connection type: Choose the VPC connection.
      • Database server: Enter the Redshift cluster endpoint from the primary Region.
      • Port: 5439
      • Database name: Enter the consumer database name.
      • Username and Password: Enter credentials (consider using AWS Secrets Manager).
    4. Choose Validate connection to test.
    5. Choose Create data source.

  1. Verify the connection and create datasets:
    1. Choose the schema and tables from the consumer database.
    2. Configure appropriate refresh schedules.
    3. Create calculations and visualizations as needed.

Performance considerations for cross-Region analytics

When implementing a cross-Region analytics architecture, be aware of the following performance implications:

  • Query performance impact – Cross-Region queries can experience higher latency than single-Region queries. To mitigate this, consider the following:
    • Use SPICE for QuickSight – Import frequently-used datasets into SPICE (Super-fast, Parallel, In-memory Calculation Engine) to help avoid repeated cross-Region queries. SPICE is the QuickSight in-memory engine that enables fast, interactive visualizations by precomputing and storing datasets locally in the QuickSight Region.
    • Implement efficient query patterns – Minimize the amount of data transferred between Regions.
    • Use appropriate caching – Enable result caching where possible.
    • Monitoring cross-Region performance – Implement monitoring to identify and address performance issues:
      • Set up Amazon CloudWatch metrics to track cross-Region query performance
      • Create dashboards to visualize latency trends
      • Establish performance baselines and alerts for degradation

Security considerations

Maintaining security in a cross-Region architecture requires additional attention:

  • Network security:
    • Limit VPC peering connections to only necessary VPCs
    • Implement restrictive security groups that allow only required traffic
    • Consider using VPC endpoints for service access when possible
  • Data access controls:
    • Use AWS Identity and Access Management (IAM) policies consistently across Regions
    • Implement fine-grained access controls in Redshift datashares
    • Enable audit logging in relevant Regions
  • Compliance monitoring:
    • Implement AWS CloudTrail in all Regions
    • Create centralized logging for cross-Region activities
    • Regularly review cross-Region access patterns

Cost implications

Before implementing a cross-Region architecture, consider these cost factors:

  • Data transfer costs – Data transfer between Regions incurs charges
  • Additional infrastructure – You might need Redshift clusters in multiple Regions
  • VPC peering costs – Data transfer costs are associated with VPC peering
  • Operational overhead – Managing multi-Region deployments requires additional resources
  • Workload-based sizing – You should size each Regional Redshift cluster according to the specific workloads it will handle

Conclusion

The cross-Region architecture described in this post addresses specific challenges related to Regional compliance requirements and global analytics needs, particularly in the following scenarios:

  • Your data must remain in a specific Region for compliance reasons
  • You have teams in different Regions who need to access and analyze this data
  • Different user groups have distinct workload requirements

The datasharing capabilities of Amazon Redshift and Regional storage options in Amazon S3 are key enablers of this solution, allowing data to remain in the required Region while still being accessible for analytics across Regions. However, it’s worth emphasizing that this architecture supports data storage in specific Regions but doesn’t prevent data from traveling between Regions during processing. Organizations concerned about data transit restrictions should evaluate additional controls to address those specific requirements. Combined with secure VPC peering connections and QuickSight visualizations, this architecture creates a complete solution that satisfies both compliance requirements and business needs.

For our financial services example, this architecture successfully enables the company to keep its customer financial data in Bahrain while providing seamless analytics capabilities to the European data science team and delivering interactive dashboards to global business leaders.

For more information, refer to Building a Cloud Security Posture Dashboard with Amazon QuickSight. For hands-on experience, explore the Amazon QuickSight Workshops. Visit the Amazon Redshift console or Amazon QuickSight console to start building your first dashboard, and explore our AWS Big Data Blog for more customer success stories and implementation patterns

Try out this solution for your own use case, and share your thoughts in the comments.


About the Authors

Donatas Kuchalskis is a Cloud Operations Architect at AWS, based in London, focusing on Financial Services customers in the UK. He helps customers optimize their AWS environments for cost, security, and resiliency while providing strategic cloud guidance. Prior to this role, he served as a Prototyping Architect specializing in Big Data and as a Specialist Solutions Architect for Retail. Before joining AWS, Donatas spent 6 years as a technical consultant in the retail sector.

Jumana Nagaria is a Prototyping Architect at AWS. She builds innovative prototypes with customers to solve their business challenges. She is passionate about cloud computing and data analytics. Outside of work, Jumana enjoys travelling, reading, painting, and spending quality time with friends and family.

AWS Weekly Roundup: Strands Agents, AWS Transform, Amazon Bedrock Guardrails, AWS CodeBuild, and more (May 19, 2025)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-strands-agents-aws-transform-amazon-bedrock-guardrails-aws-codebuild-and-more-may-19-2025/

Many events are taking place in this period! Last week I was at the AI Week in Italy. This week I’ll be in Zurich for the AWS Community Day – Switzerland. On May 22, you can join us remotely for AWS Cloud Infrastructure Day to learn about cutting-edge advances across compute, AI/ML, storage, networking, serverless technologies, and global infrastructure. Look for events near you for an opportunity to share your knowledge and learn from others.

What got me particularly excited last Friday was the introduction of Strands Agents, an open source SDK that you can use to build and run AI agents in just a few lines of code. It can scale from simple to complex use cases, including local development and production deployment. By default, it uses Amazon Bedrock as model provider, but many others are supported, including Ollama (to run models locally), Anthropic, Llama API, and LiteLLM (to provide a unified interface for other providers such as Mistral). With Strands, you can use any Python function as a tool for your agent with the @tool decorator. Strands provides many example tools for manipulating files, making API requests, and interacting with AWS APIs. You can also choose from thousands of published Model Context Protocol (MCP) servers, including this suite of specialized MCP servers that help you get the most out of AWS. Multiple teams at AWS already use Strands for their AI agents in production, including Amazon Q Developer, AWS Glue, and VPC Reachability Analyzer. Read it all in Clare’s post.

Strands Agents SDK agentic loop

Last week’s launches
Here are the other launches that got my attention:

Additional updates
Here are some additional projects, blog posts, and news items that you might find interesting:

  • Securing Amazon S3 presigned URLs for serverless applications – Focusing on the security ramifications of using Amazon S3 presigned URLs, explaining mitigation steps that developers can take to improve the security of their systems using S3 presigned URLs, and walking through an AWS Lambda function that adheres to the provided recommendations.
    Architectural diagram.
  • Running GenAI Inference with AWS Graviton and Arcee AI Models – While large language models (LLMs) are capable of a wide variety of tasks, they require compute resources to support hundreds of billions and sometimes trillions of parameters. Small language models (SLMs) in contrast typically have a range of 3 to 15 billion parameters and can provide responses more efficiently. In this post, we share how to optimize SLM inference workloads using AWS Graviton based instances.
    AWS Graviton processors.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Dubai (May 21), Tel Aviv (May 28), Singapore (May 29), Stockholm (June 4), Sydney (June 4–5), Washington (June 10-11), and Madrid (June 11)
  • AWS Cloud Infrastructure Day – On May 22, discover the latest innovations in AWS Cloud infrastructure technologies at this exclusive technical event.
  • AWS re:Inforce – Mark your calendars for AWS re:Inforce (June 16–18) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity.
  • AWS Partners Events – You’ll find a variety of AWS Partner events that will inspire and educate you, whether you’re just getting started on your cloud journey or you’re looking to solve new business challenges.
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Zurich, Switzerland (May 22), Bengaluru, India (May 23), Yerevan, Armenia (May 24), Milwaukee, USA (June 5), and Nairobi, Kenya (June 14)

That’s all for this week. Check back next Monday for another Weekly Roundup!

Danilo

AWS CloudTrail network activity events for VPC endpoints now generally available

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-cloudtrail-network-activity-events-for-vpc-endpoints-now-generally-available/

Today, I’m happy to announce the general availability of network activity events for Amazon Virtual Private Cloud (Amazon VPC) endpoints in AWS CloudTrail. This feature helps you to record and monitor AWS API activity traversing your VPC endpoints, helping you strengthen your data perimeter and implement better detective controls.

Previously, it was hard to detect potential data exfiltration attempts and unauthorized access to the resources within your network through VPC endpoints. While VPC endpoint policies could be configured to prevent access from external accounts, there was no built-in mechanism to log denied actions or detect when external credentials were used at a VPC endpoint. This often required you to build custom solutions to inspect and analyze TLS traffic, which could be operationally costly and negate the benefits of encrypted communications.

With this new capability, you can now opt in to log all AWS API activity passing through your VPC endpoints. CloudTrail records these events as a new event type called network activity events, which capture both control plane and data plane actions passing through a VPC endpoint.

Network activity events in CloudTrail provide several key benefits:

  • Comprehensive visibility – Log all API activity traversing VPC endpoints, regardless of the AWS account initiating the action.
  • External credential detection – Identify when credentials from outside your organization are accessing your VPC endpoint.
  • Data exfiltration prevention – Detect and investigate potential unauthorized data movement attempts.
  • Enhanced security monitoring – Gain insights into all AWS API activity at your VPC endpoints without the need to decrypt TLS traffic.
  • Visibility for regulatory compliance – Improve your ability to meet regulatory requirements by tracking all API activity passing through.

Getting started with network activity events for VPC endpoint logging
To enable network activity events, I go to the AWS CloudTrail console and choose Trails in the navigation pane. I choose Create trail to create a new one. I enter a name in the Trail name field and choose an Amazon Simple Storage Service (Amazon S3) bucket to store the event logs. When I create a trail in CloudTrail, I can specify an existing Amazon S3 bucket or create a new bucket to store my trail’s event logs.

If you set Log file SSE-KMS encryption to Enabled, you have two options: Choose New to create a new AWS Key Management Service (AWS KMS) key or choose Existing to choose an existing KMS key. If you chose New, you need to type an alias in the AWS KMS alias field. CloudTrail encrypts your log files with this KMS key and adds the policy for you. The KMS key and Amazon S3 must be in the same AWS Region. For this example, I use an existing KMS key. I enter the alias in the AWS KMS alias field and leave the rest as default for this demo. I choose Next for the next step.

In the Choose log events step, I choose Network activity events under Events. I choose the event source from the list of AWS services, such as cloudtrail.amazonaws.com, ec2.amazonaws.com, kms.amazonaws.com, s3.amazonaws.com, and secretsmanager.amazonaws.com. I add two network activity event sources for this demo. For the first source, I select ec2.amazonaws.com option. For Log selector template, I can use templates for common use cases or create fine-grained filters for specific scenarios. For example, to log all API activities traversing the VPC endpoint, I can choose the Log all events template. I choose Log network activity access denied events template to log only access denied events. Optionally, I can enter a name in the Selector name field to identify the log selector template, such as Include network activity events for Amazon EC2.

As a second example, I choose Custom to create custom filters on multiple fields, such as eventName and vpcEndpointId. I can specify specific VPC endpoint IDs or filter the results to include only the VPC endpoints that match specific criteria. For Advanced event selectors, I choose vpcEndpointId from the Field dropdown, choose equals as Operator, and enter the VPC endpoint ID. When I expand the JSON view, I can see my event selectors as a JSON block. I choose Next and after reviewing the selections, I choose Create trail.

After it’s configured, CloudTrail will begin logging network activity events for my VPC endpoints, helping me analyze and act on this data. To analyze AWS CloudTrail network activity events, you can use the CloudTrail console, AWS Command Line Interface (AWS CLI), and AWS SDK to retrieve relevant logs. You can also use CloudTrail Lake to capture, store and analyze your network activity events. If you are using Trails, you can use Amazon Athena to query and filter these events based on specific criteria. Regular analysis of these events can help you maintain security, comply with regulations, and optimize your network infrastructure in AWS.

Now available
CloudTrail network activity events for VPC endpoint logging provide you with a powerful tool to enhance your security posture, detect potential threats, and gain deeper insights into your VPC network traffic. This feature addresses your critical needs for comprehensive visibility and control over your AWS environments.

Network activity events for VPC endpoints are available in all commercial AWS Regions.

For pricing information, visit AWS CloudTrail pricing.

To get started with CloudTrail network activity events, visit AWS CloudTrail. For more information on CloudTrail and its features, refer to the AWS CloudTrail documentation.
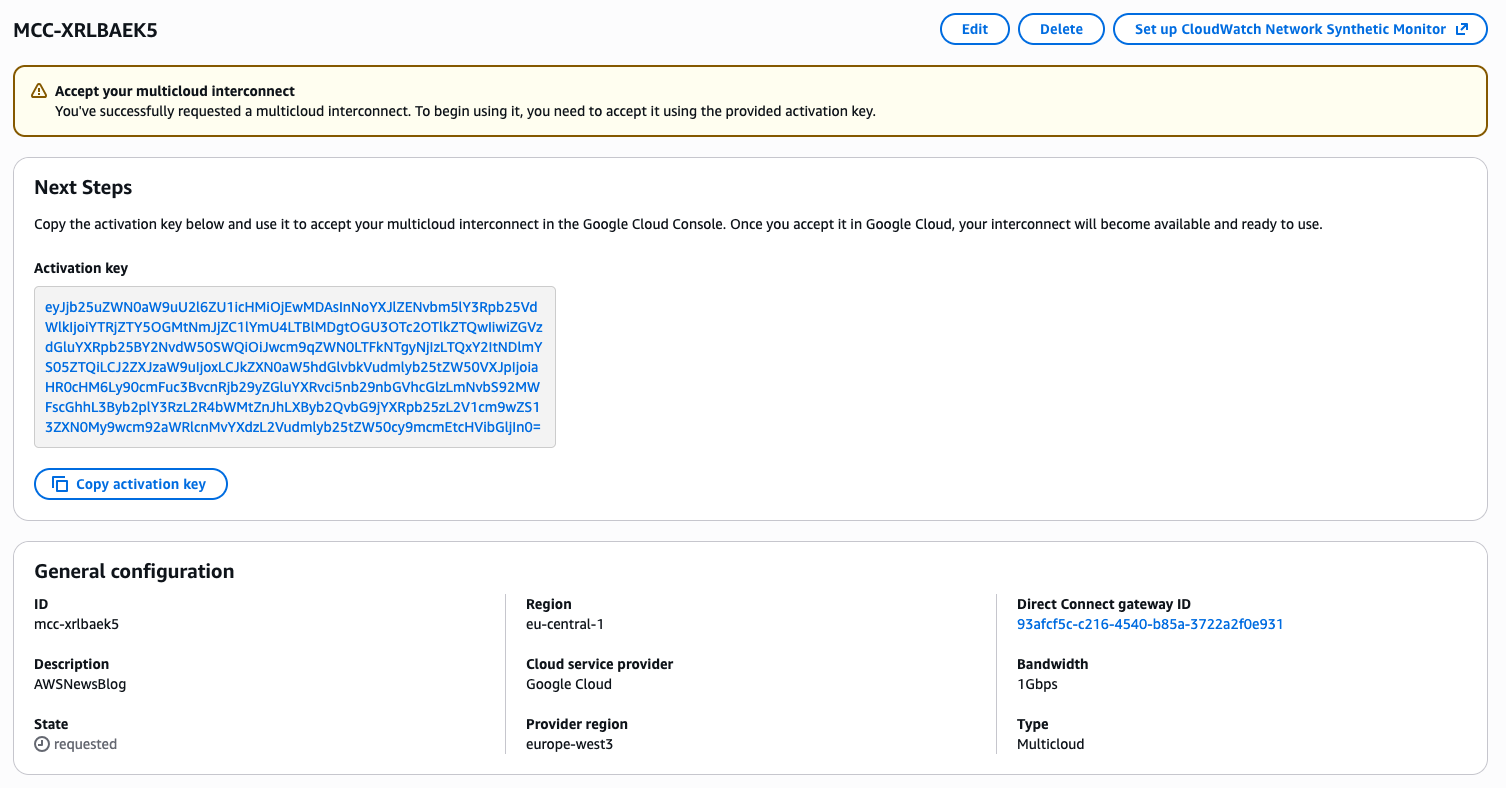
— Esra

Securely share AWS resources across VPC and account boundaries with PrivateLink, VPC Lattice, EventBridge, and Step Functions

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/securely-share-aws-resources-across-vpc-and-account-boundaries-with-privatelink-vpc-lattice-eventbridge-and-step-functions/

At some point, every AWS customer tells me that they have the desire to move into the future as quickly as possible. They want to simplify their modernization efforts, drive growth, and adapt to the cloud, while also reducing costs as they proceed. These customers typically have a large suite of legacy applications, possibly running on-premises, that are running on diverse technology stacks managed by disparate parts of the organization. To make things even more challenging, these organizations often have to meet stringent security and compliance requirements.
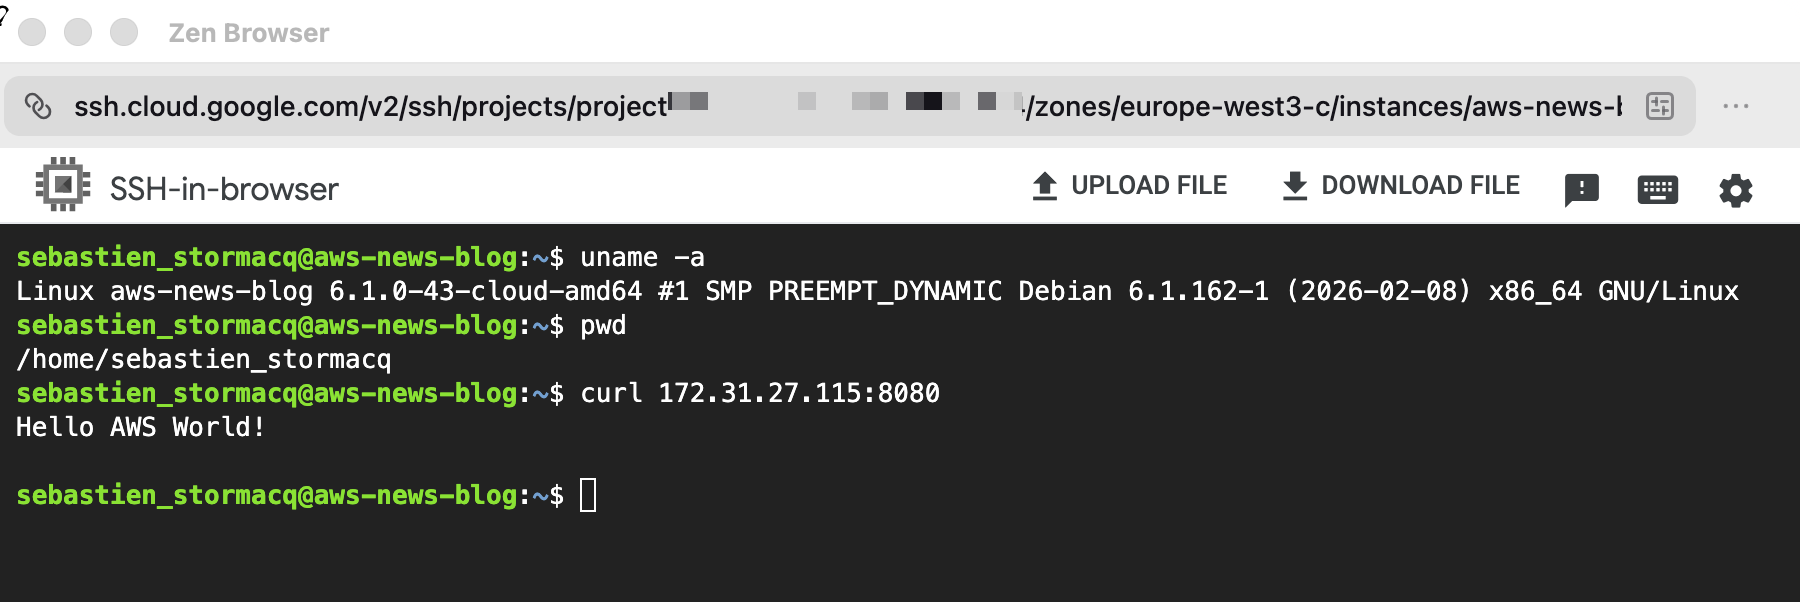
Prepare to Share
You can now share AWS resources such as Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS) container services, and your own HTTPS services across Amazon Virtual Private Cloud (Amazon VPC) and AWS account boundaries and use them to build event-driven apps via Amazon EventBridge and orchestrate workflows with AWS Step Functions. You can update your existing workloads, connect your modern cloud-native apps to on-premises legacy systems, with all communication routed across private endpoints and networks.

These new features build on Amazon VPC Lattice and AWS PrivateLink, and give you a lot of new options to design and control your network, along with some cool new ways to integrate and orchestrate across all of your technology stacks. For example, you can build hybrid event-driven architectures that make use of your existing on-premises applications.

Today, some customers use AWS Lambda functions or Amazon Simple Queue Service (Amazon SQS) queues to transfer data into VPCs. This undifferentiated heavy lifting can now be replaced with a simpler and more efficient solution.
Bringing all of this together, you get a set of services that will help you to accelerate your modernization efforts and simplify integration between your applications, regardless of where they are situated. EventBridge and Step Functions work hand-in-hand with PrivateLink and VPC Lattice to enable integration of public and private HTTPS-based applications into your event-driven architectures and workflows.

Here are the essential terms and concepts:

Resource Owner VPC – A VPC that has resources to be shared. The owner of this VPC creates a Resource Gateway with one or more associated Resource Configurations, then uses AWS Resource Access Manager (RAM) to share the Resource Configuration with the Resource Consumer, such as another AWS account, or a developer building event-driven architectures and workflows using EventBridge and Step Functions. Let’s define the Resource Owner as the person (maybe you) in your organization who is responsible for the care and feeding of this VPC.

Resource Gateway – Provides a point of ingress to a VPC so that clients can access resources in the Resource Owner VPC, as indicated by the Resource Configurations that are associated with the gateway. One Resource Gateway can make multiple resources available.

Resource – This can be a HTTPS endpoint, a database, a database cluster, an EC2 instance, an Application Load Balancer in front of multiple EC2 instances, an ECS service discoverable via AWS Cloud Map, an Amazon Elastic Kubernetes Service (Amazon EKS) service behind a Network Load Balancer, or a legacy service running in the Resource Owner VPC or running in on-premises across AWS Site-to-Site VPN or AWS Direct Connect.

Resource Configuration – Defines a set of resources that can be accessed through a particular Resource Gateway. The resources can be referenced by IP address, DNS name, or (for AWS resources) an ARN.

Resource Consumer – The person in your organization who is responsible for building applications that connect with and consume services provided by resources in a Resource Owner VPC.

Sharing Resources
You can put all of this power to use in a lot of different ways; I’ll focus on one for this post.

First, I will play the role of the Resource Owner. I click Resource gateways in the VPC Console, see that I don’t have a gateway, and click Create resource gateway to get started:

I assign a name (main-rg) and an IP address type, then pick the VPC and the private subnets where the gateway will have a presence (this is a one-shot selection that cannot be changed without creating a new Resource Gateway). I also choose up to five security groups to control inbound traffic:

I scroll down, assign any desired tags, and click Create resource gateway to proceed:

My new gateway is active within seconds; I nod in appreciation and click Create resource configuration to move ahead:

Now I need to create my first Resource Configuration. Let’s say that I have a HTTPS service running on an EC2 instance on a private subnet in my Resource Owner VPC. I assign a DNS name to the service and use a Amazon Route 53 Alias record which returns the IP address of the instance:
I am using a public hosted zone in this example. We already working on support for private hosted zones.

With DNS all set up, I click Create resource configuration to move ahead. I enter a name (rc-service1), choose Resource as the type, and select the Resource Gateway that I created earlier:

I scroll down and define my EC2 instance as a resource, entering the DNS name and setting up sharing for ports 80 and 443:

Now I take a small detour, and hop over to the RAM Console to create a Resource Share so that other AWS accounts can access the resources (this is optional, and only relevant for cross-account scenarios). I could create one Resource Share for each service, but in most cases I would create one share and use it to package up a collection of related services. I’ll do that, and call it shared-services:

Returning from my detour, I refresh the list of resource shares, pick the one that I created, and click Create resource configuration:

The resource configuration is ready within seconds.

Recap and Planning Time
Before moving ahead, let’s do a quick recap and make some plans. Here’s what I (in the role of Resource Provider) have so far:

  • MainVPC – My Resource Owner VPC.
  • main-rg – A Resource Gateway in MainVPC.
  • rc-service1 – The Resource Configuration for main-rg.
  • service1 – An HTTPS service hosted on an EC2 instance in a private subnet of MainVPC, at a fixed IP address.

Ok, so what’s next?

Share – This is the first and most obvious use use. I can use AWS Resource Access Manager (RAM) to share the Resource Configuration with another AWS account and access the service from another VPC. On the other side (as the Resource Consumer), I take a couple of quick steps to connect to the service that has been shared with me:

  • Service Network – I can create a service network, add the Resource Configuration to the Service Network, and create a VPC endpoint in a VPC to connect to the service network.
  • Endpoint – I can create a VPC endpoint in a VPC and access the shared resource via the endpoint.

Modernize – I can remove my legacy Lambda or SQS integration to get rid of some undifferentiated heavy lifting.

Build – I can use EventBridge and Step Functions to build event-driven architectures and orchestrate applications. I’ll take this option!

Accessing Private Resources with EventBridge and Step Functions
EventBridge and Step Functions already make it easy access to public HTTPS endpoints such as those from SaaS providers like Slack, Salesforce, and Adobe. With today’s launch, consuming private HTTPS services is just as easy.

As a Resource Consumer, I simply create an EventBridge connection, reference a Resource Configuration that was shared with me, and call the service from my event-driven application. Everything that I already know still applies, and I now have the new-found power to access private services.
To create the EventBridge connection, I open the EventBridge console and click Connections in the Integration  menu:

I review my existing connections (none so far), then click Create connection to move ahead:

I enter a name (MyService1) and a description for my connection, select Private as the API type, and choose the Resource Configuration that I created earlier:

Scrolling down, I need to configure the authorization for the service that I am connecting to. I select Custom configuration and Basic authorization, and enter the Username and Password for my service. I also add Action=Forecast to the query string (as you can see there are a lot of options for authorization), and click Create:

The connection is created and ready within minutes. Then I use it in my Step Functions workflows by using the HTTP Task, selecting the connection, entering the URL of my API endpoint, and choosing an HTTP method:

And that’s all there is to it: your Step Functions workflows can now make use of Private Resources!

I can also use this connection as an EventBridge API destination target in Event Buses and Pipes.

Things to Know
Here a couple of things to know about these cool new features:

Pricing – Existing pricing for Step Functions, EventBridge, PrivateLink, and VPC Lattice apply including the per-GB charge for data transfer into the VPC.

Regions – You can create and use Resource Gateways and Resource Configurations in 21 AWS Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Milan, Paris, Stockholm), Middle East (Bahrain), and South America (São Paulo).

In the Works – As I noted earlier, we are already working on support for private hosted zones. We are also planning to support access to other types of AWS resources through EventBridge and Step Functions .

Jeff;

Streamline container application networking with built-in Amazon ECS support in Amazon VPC Lattice

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/streamline-container-application-networking-with-native-amazon-ecs-support-in-amazon-vpc-lattice/

Since its launch, Amazon VPC Lattice has streamlined complex networking tasks. As a result, my perspective on how to build and connect modern, multi-service applications has changed. As my colleague Danilo wrote in his post announcing the general availability of VPC Lattice:

“By using VPC Lattice, you can focus on your application logic and improve productivity and deployment flexibility with consistent support for instances, containers, and serverless computing.”

Today, we’re announcing Amazon VPC Lattice built-in support for Amazon Elastic Container Service (Amazon ECS). With this new built-in integration, Amazon ECS services can now be directly associated with VPC Lattice target groups without the need for intermediate load balancers.

Here’s a quick look at how you can find Amazon VPC Lattice integration while creating an Amazon ECS service:

The Amazon VPC Lattice integration with Amazon ECS works by registering and deregistering IP addresses from ECS tasks within a service as targets in a VPC Lattice target group. As ECS tasks for the service are launched, Amazon ECS will automatically register those tasks to the VPC Lattice target group.

Furthermore, if ECS tasks fail VPC Lattice health checks, Amazon ECS will automatically replace the tasks. Also, if any task is terminated or scales down, it’s removed from the target group.

Using the Amazon VPC Lattice integration
Let me walk you through how to use this new integration. In the following demo, I will deploy a simple application server running as an ECS service and configure the integration with VPC Lattice. Then, I’ll test the application server by connecting to the VPC Lattice domain name without having to configure additional load balancers on Amazon ECS.
Before I can start with this integration, I need to make sure Amazon ECS will have the required permissions to register and deregister targets into VPC Lattice. To learn more, please visit the Amazon ECS infrastructure IAM role documentation page.

To use the integration with VPC Lattice, I need to define a task definition with at least one container and one port mapping. This is an example of my task definition.

{
    "containerDefinitions": [
        {
            "name": "webserver",
            "image": "public.ecr.aws/ecs-sample-image/amazon-ecs-sample:latest",
            "cpu": 0,
            "portMappings": [
                {
                    "name": "web-80-tcp",
                    "containerPort": 80,
                    "hostPort": 80,
                    "protocol": "tcp",
                    "appProtocol": "http"
                }
            ],
            ...
            *redacted for brevity*
}

Then, I navigate to my ECS cluster and choose Create.

Next, I need to select the task definition and assign the service name.

In the VPC Lattice integration section, I choose Turn on VPC Lattice to start configuring the target group for VPC Lattice. I don’t need to specify a load balancer because I’ll use VPC Lattice. By default, VPC Lattice will use a round-robin routing algorithm to route requests to healthy targets.

Now, I can start defining the integration for my ECS service in VPC Lattice. First, I select the infrastructure role for Amazon ECS. Then, I need to select the virtual private cloud (VPC) where I want my service to run. After that, I need to define the Target groups that will receive traffic. After I’m done configuring the service with VPC Lattice integration, I create this service.

After a few minutes, I have my ECS service ready. I navigate to the service and choose Configuration and networking. If I scroll down to the VPC Lattice section, I can see the VPC Lattice target group created.

To get more information on this target group, I select the target group name, which will redirect me to the VPC Lattice target group page. Here, I can see that Amazon ECS successfully registered the IP address of the running task.

Now, I need to create a VPC Lattice service and service network. My preference is always to create the VPC Lattice service then associate with the VPC Lattice service network later on. So, let’s do that.

I choose Services under the VPC Lattice section and choose Create service.

I fill in all the details required to create a VPC Lattice service and choose Next.

Then, I add a listener, and for the Forward to target group on the Listener default action, I select the newly created target group.

On the next page, because I’m going to create the VPC Lattice service network later, I skip this step and choose Next, review the configurations, and create the service.

With VPC Lattice service created, now it’s time to create VPC Lattice service networks. I navigate to Service networks under the VPC Lattice section and choose Create service network.

First, I fill the VPC Lattice service network name.

Then, on the Service associations page, I select the service that I have created.

I associate this service network to my VPC as well as the security group.

For the simplicity of this demo, I set None for the Auth type. However, I highly recommend you to read how you can use IAM to manage access to VPC Lattice. Then, I choose Create service network.

At this stage, we have everything setup for this integration. My VPC Lattice service network is now associated with my VPC Lattice service and my VPC.

With everything set up, I copy the Domain name from my VPC Lattice service page.

Then, to access the service, I log in to the instance in the same VPC and call the service by using the domain name from VPC Lattice.

[ec2-user@ ~]$ curl http://service-a-XYZ.XYZ.vpc-lattice-svcs.XYZ.on.aws

"Hello there! I'm Amazon ECS."

One thing to note is if you’re not receiving traffic to your Amazon ECS workloads, check the security groups as described in the Control traffic in VPC Lattice using security groups documentation page.

I’m personally excited about this integration because it unlocks various possibilities while streamlining application architectures and improving overall system reliability. Now that all AWS compute types are inherently supported in VPC Lattice, I can unify services across all my ECS clusters, AWS accounts, and VPCs.

Things to know
Here are a couple of important points to note:

Try this new capability of Amazon VPC Lattice today and see how it can streamline your container application communication running on Amazon ECS.

Happy building!

Donnie Prakoso