If you do any kind of video streaming, encoding and storing your data is one of your main challenges. Encoding videos in various formats and resolutions for different devices and platforms can be a resource-intensive task, and setting up and maintaining on-premises encoding infrastructure can be expensive.
Today, we’re excited to announce an expanded partnership with Qencode, a media services platform that enables users to build powerful video solutions, including solutions to the challenges of transcoding, live streaming, and media storage. The expanded partnership embeds the Backblaze Partner API within the Qencode platform, making it frictionless for users to add cloud storage to their media production workflows.
What Is Qencode?
Qencode is a media services platform founded in 2017 that assists with digital video transformation. The Qencode API provides developers within the over-the-top (OTT), broadcasting, and media & entertainment sectors with scalable and robust APIs for:
Video transcoding
Live streaming
Content delivery
Media storage
Artificial intelligence
Qencode + Backblaze
Recognizing the growing demand for integrated and efficient cloud storage within media production, Qencode and Backblaze built an alliance which creates a new paradigm for cutting-edge video APIs fortified by a reliable and efficient cloud storage solution. This integration empowers flexible workflows consisting of uploading, transcoding, storing, and delivering video content for media and OTT companies of all sizes. By integrating the platforms, this partnership provides top-tier features while simplifying the complexities and reducing the risks often associated with innovation.
We want to set new standards for value in an industry that is fragmented and complex. By merging Qencode’s advanced video processing capabilities with Backblaze’s reliable cloud storage, we’re addressing a critical industry need for seamless integration and efficiency. Integrating Backblaze’s Partner API takes our platform to the next level, providing users with a single, streamlined interface for all their video and media needs.
Murad Mordukhay, CEO of Qencode
Qencode + Backblaze Use Cases
The easy-to-use interface and affordability make Qencode an ideal choice for businesses who need video processing at scale without compromising spend or flexibility. Qencode enables businesses of all sizes to customize and control a complete end-to-end solution, from sign-on to billing, which includes seamless access to Backblaze storage through the Qencode software as a service (SaaS) platform.
Simplifying the User Experience
Expanding this partnership with Qencode takes our API technology a step further in making cloud storage more accessible to businesses whose mission is to simplify user experience. We are excited to work with a specialist like Qencode to bring a simple and low cost storage solution to businesses who need it the most.
Editor’s note: Since it was published in 2019, this post has been updated in 2021 and 2023 with the latest information to help you take advantage of SSDs.
Solid-state drives (SSDs) have become the norm for most laptops and desktops, replacing the older hard disk drives (HDDs) that had been in use for decades previously. If your computer still relies on an HDD, it might be time to consider upgrading to an SSD for improved performance.
Upgrading to an SSD can give your computer a significant speed and responsiveness boost, especially if your machine is more than a few years old. However, before taking the plunge, it’s essential to weigh practical considerations. Let’s take a closer look at SSDs and the factors you should consider.
What Is an SSD?
An SSD is a type of data storage device used in computers and other electronic devices. Unlike traditional HDDs, which use spinning disks and mechanical read/write heads to store and retrieve data, SSDs rely on NAND-based flash memory to store information. This flash memory is similar to the kind used in USB drives and memory cards, but it’s optimized for higher performance and reliability.
Refresher: What Is NAND?
NAND stands for “Not And.” It’s a type of logic gate used in digital circuits, specifically in memory and storage devices. In the context of NAND-based flash memory used in SSDs, the term NAND refers to the electronic structure of the memory cells that store data. The name NAND comes from its logical operation, which is the complement of the AND operation. NAND flash memory is a type of non-volatile storage, meaning it retains data even when the power is turned off, which makes it well-suited for use with things like SSDs and other data storage devices. That’s different from the regular RAM in your computer, which is reset when you turn off or restart the computer.
Compared to HDDs, SSDs are more shock resistant (due to their lack of moving parts) and are less likely to be affected by magnetic fields. They also offer faster data access times, quicker boot-up and application load times, and better overall responsiveness.
Because of their speed and efficiency, SSDs have become the preferred choice for many computing applications, ranging from laptops and desktops to servers and data centers. They are especially useful in situations where speed and reliability are crucial, such as in gaming, content creation, and tasks involving large data transfers. Despite typically offering less storage capacity compared to HDDs of similar cost, SSD performance benefits often outweigh the storage trade-off, making them a popular choice.
Depending on the task at hand, SSDs can be up to 10 times faster than their HDD counterparts. Replacing your hard drive with an SSD is one of the best things you can do to dramatically improve the performance of your older computer.
Samsung 870 QVO SATA III 2.5″ SSD 1TB.
Without any moving parts, SSDs operate more quietly, more efficiently, and with fewer breakable things than hard drives that have spinning platters. Read and write speeds for SSDs are much better than hard drives, resulting in noticeably faster operations.
For you, that means less time waiting for stuff to happen. An SSD is worth looking into if you’re frequently seeing a spinning wheel cursor on your computer screen. Modern operating systems rely more on virtual memory management, utilizing temporary swap files that are written to the disk. A faster SSD minimizes the performance impact caused by this process.
If you have just one drive in your laptop or desktop, you could replace an HDD or small SSD with a 1TB SSD for less than $40. For those dealing with substantial amounts of data, concentrating on replacing the drive that houses your operating system and applications can yield a significant speed boost. Put your working data on additional internal or external hard drives, and you’re ready to tackle a mountain of photos, videos, or supersized databases. Just be sure to implement a backup plan to make sure you keep a copy of that data safe on additional local drives, network attached drives, or in the cloud.
Are There Any Reasons Not to Upgrade to an SSD?
If SSDs are so much better than hard drives, why aren’t all drives SSDs? The two biggest reasons are cost and capacity. SSDs are more expensive than hard drives. A 1TB SSD or HDD now cost about the same, $30–$50, with HDDs being slightly less, maybe around $25.
That’s not much of a difference, but as drive capacity gets larger, the cost differential gets increasingly larger. For example, an 8TB HDD drive runs $120–$180, while 8TB SSDs start at around $350. In short, while upgrading the 1TB internal hard drive on your computer to an SSD is cost effective, the same may not be true for replacing larger capacity drives, like those used in external drives, unless the increased speed is worth the increased cost.
Whether your computer can use an SSD is another question. It all depends on the computer’s age and how it was designed. Let’s take a look at that question next.
How Do You Upgrade to an SSD?
Does your computer use a regular off-the-shelf SATA HDD? If so, you can upgrade it with an SSD.
SSDs are compatible with both Macs and PCs. All current Mac laptops come with SSDs. Both iMacs and Mac Pros come with SSDs as well. Around 2010, Apple started moving to only SSD storage on most of its devices. That said, some Mac desktop computers continued to offer the option of both SSD and HDD storage until 2020, a setup they called a Fusion Drive.
Note that as of November 2021, Apple does not offer any Macs with a Fusion Drive. Basically, if you bought your device before 2010 or you have a desktop computer from 2021 or earlier, there’s a chance you may be using an HDD.
Determine Your Disk Type in a Mac
To determine what kind of drive your Mac uses, click on the Apple menu and select About This Mac.
Avoid the pitfall of selecting the Storage tab in the top menu. What you’ll find is that the default name of your drive is “Macintosh HD” which is confusing, given that they’re referring to the internal storage of the computer as a hard drive when (in most cases), your drive is an SSD. While you can find information about your drive on this screen, we prefer the method that provides maximum clarity.
So, on the Overview screen, click System Report. Bonus: You’ll also see what type of processor you have and your macOS version (which will be useful later).
Once there, select the Storage tab, then the volume name you want to identify. You should see a line called Medium Type, which will tell you what kind of drive you have.
Determine Your Disk Type in a PC
To determine your disk type in a Windows PC, first open the Task Manager in Windows:
Right-click the Start button and click Run. In the Run Command window, type dfrgui and click OK.
On the next screen, the type of drive will be listed under the Media Type column.
Can I Upgrade to a Better SSD?
Even if your computer already has an SSD, you may be able to upgrade it with a larger, faster SSD model. Besides SATA-based hard drive replacements, some later model PCs can be upgraded with M.2 SSDs, which look more like RAM chips than hard drives.
Some Apple laptops made before 2016 that already shipped with SSDs can be upgraded with larger ones. However, you will need to upgrade to a Mac-specific SSD. Check Other World Computing and Transcend to find ones designed to work. Apple laptop models made after 2016 have SSDs soldered to the motherboard, so you’re stuck with what you have.
M.2 SSD.
How to Install an SSD
If you’re comfortable tinkering with your computer’s guts, upgrading it with an SSD is a pretty common do-it-yourself project. Many companies offer hassle-free plug-and-play SSD replacements. Check out Amazon or NewEgg and you’ll have an embarrassment of riches. The choice is yours: Samsung, SanDisk, Crucial, and Toshiba are all popular SSD makers. There are many others, too.
However, if computer hardware isn’t your forte, it might not be worth the effort to learn from scratch. SSD upgrades are such a common aftermarket improvement most independent computer repair and service specialists will take on the task if you’re willing to pay them. Some throw in a data transfer if you’re lucky, or a skilled negotiator. Ask your friends and colleagues for recommendations. You can also hit up services like Angi to find someone.
If you are DIY inclined, YouTube has tons of walkthroughs like this one for desktop PCs, this one for laptops, and this one aimed at Mac users.
HDD/SSD to 3.5″ drive bay adapter.
Many SSDs replace 2.5 inch HDDs. Those are the same drives you find in laptop computers and even small desktop models. Have a desktop computer that uses a 3.5 inch hard drive? You may need to use a 2.5 inch to 3.5 inch mounting adapter.
A Word on SSD Compatibility
Beyond the drive size, it’s a good idea to check to see if the SSD you want to buy is compatible with your laptop or desktop, especially if your system is older than a couple of years. Here are articles from Tom’s Hardware and ShareUs which can help with that.
How to Migrate to an SSD
Buying a replacement SSD is the first step. Moving your data onto the SSD is the next step. To achieve this, you need two essential components: cloning software and an external drive case, sled, or enclosure. These tools enable you to connect your SSD to your computer through its USB port or another data transfer interface.
Cloning software creates an exact replica of your internal hard drive’s data. Once this data is successfully migrated to the SSD, you can then insert the new drive into your computer. I prefer to clone a hard drive onto an SSD whenever possible. When executed correctly, a cloned SSD retains its bootable capabilities, providing a true plug-and-play experience. Just copying files between the two drives instead may not copy all the data you need to get the computer to boot with the new drive.
How to Clone a Hard Drive to an SSD
When you buy a new SSD or even a fresh hard drive, it’s unlikely that the operating system you need will be pre-installed. Cloning your existing hard drive fixes that. However, there are instances where this may not be feasible. For example, maybe you’ve installed the SSD in a computer that previously had a bad hard drive. If so, you can do what’s called a clean install and start fresh. Different operating system providers offer distinct guidelines for this procedure. Here’s a link to Microsoft’s clean install procedure, and Apple’s clean install instructions.
As we said at the outset, SSDs tend to come at a higher cost per gigabyte compared to traditional hard drives. You may not be able to afford as large an SSD as your current drive, so make sure your data will fit on your new drive. If it won’t, you might have to pare down first. Additionally, it’s wise to leave some room for expansion. The last thing you want to do is immediately max out your new, fast drive.
Now that you’ve successfully cloned your drive and integrated the SSD into your system, what do you do with the old drive? If it’s still functional, repurposing the external drive chassis utilized during migration is a practical option. It can continue to serve as a standalone external drive or become part of a disk array, such as a network attached storage (NAS) device. You can use it for local back up—something we strongly recommend doing—in addition to using cloud back up like Backblaze. Or, just use it for extra storage needs, like for your photos or music.
Make Sure to Back Up
SSD upgrades are commonplace, but that doesn’t mean things don’t go wrong that can stop you dead in your tracks. If your computer is working fine before the SSD upgrade, make sure you have a complete backup of your computer to restore from in the event something goes wrong.
More Questions About SSDs?
You might enjoy reading other posts in our SSD 101 series.
Over the coming months, Backblaze will make big updates and upgrades to both our products—B2 Cloud Storage and Computer Backup. Considering the volume of new stuff on the horizon, I’m dropping into the blog today to explain what’s happening, when, and why for our customers as well as any others who are considering adopting our services. Here’s what’s new.
B2 Cloud Storage Updates
Price, Egress, and Product Upgrades
Meeting and exceeding customers’ needs for building applications, protecting data, supporting media workflows, and more is the top priority for B2 Cloud Storage. To further these efforts, we’ll be implementing the following updates:
Price Changes
Storage Price: Effective October 3, 2023, we are increasing the monthly pay-as-you-go storage rate from $5/TB to $6/TB. The price of B2 Reserve will not change.
Free Egress: Also effective October 3, we’re making egress free (i.e. free download of data) for all B2 Cloud Storage customers—both pay-as-you-go and B2 Reserve—up to three times the amount of data you store with us, with any additional egress priced at just $0.01/GB. Because supporting an open cloud environment is central to our mission, expanding free egress to all customers so they can move data when and where they prefer is a key next step.
Backblaze B2 Upgrades
From Object Lock for ransomware protection, to Cloud Replication for redundancy, to more data centers to support data location needs, Backblaze has consistently improved B2 Cloud Storage. Stay tuned for more this fall, when we’ll announce upload performance upgrades, expanded integrations, and more partnerships.
Things That Aren’t Changing
Storage pricing on committed contracts, B2 Reserve pricing, and unlimited free egress between Backblaze B2 and many leading content delivery network (CDN) and compute partners are all not changing.
Why the Changes for B2 Cloud Storage?
1. Continuing to provide the best cloud storage.
I am excited that B2 Cloud Storage continues to be the best high-quality and low-cost alternative to traditional cloud providers like AWS for businesses of all sizes. After seven years in service with no price increases, the bar was very high for considering any change to our pricing. We invest in making Backblaze B2 a better cloud storage provider every day. A price increase enables us to continue doing so into the future.
2. Advancing the freedom of customers’ data.
We’ve heard from customers that one of the greatest benefits of B2 Cloud Storage is freedom—freedom from complexity, runaway bills, and data lock-in. We wanted to double down on these benefits and further empower our customers to leverage the open cloud to use their data how and where they wish. Making egress free supports all these benefits for our customers.
Backblaze Computer Backup
Price, Version History, Version 9.0, and Admin Upgrades
To expand our ability to provide astonishingly easy computer backup that is as reliable as it is trustworthy and affordable, we’re instituting the following updates to Backblaze Computer Backup and sharing some upcoming product upgrades:
Computer Backup Pricing: Effective October 3, new purchases and renewals will be $9/month, $99/year, and $189 for two-year subscription plans, and Forever Version History pricing will be $0.006/GB.
Free One Year Extended Version History: Also effective October 3, all Computer Backup licenses may add One Year Extended Version History, previously a $2 per month expense, for free. Being able to recover deleted or altered files up to a year later saves Computer Backup users from huge headaches, and now this benefit is available to all subscribers. Starting October 3, log in to your account and select One Year of Extended Version History for free.
Version 9.0: In September, the release of Version 9.0 will go live. Among some improvements to performance and usability, this release includes a highly requested new local restore experience for end users. We’ll share all the details with you in September when Version 9.0 goes live.
Groups Administration Upgrades: In addition to Version 9.0, we’ve got an exciting roadmap of upgrades to our Groups functionality aimed at serving our growing and evolving customer base. For those who need to manage everything from two to two thousand workstations, we’re excited to offer more peace of mind and control with expanded tools built for the enterprise at a price still ahead of the competition.
Why the Change for Computer Backup?
Since launching Computer Backup in 2008, we’ve stayed committed to a product that backs up all your data automatically to the cloud for a flat rate. Over the following 15 years, the average amount of data stored per user has grown tremendously, and our investments to build out our storage cloud to support that growth has increased to keep pace.
At the same time, we’ve continued to invest in improving the product—as we have been recently with the upcoming release of Version 9.0, in our active development of new Group administration features, and in the free addition of optional One Year Extended Version history for all users. And, we still have more to do to ensure our product consistently lives up to its promise.
To continue offering unlimited backup, innovating, and adding value to the best computer backup service, we need to align our pricing with our costs.
Thank You
We understand how valuable your data is to your business and your life, and the trust you place in Backlaze every day is not lost on me. We are deeply committed to our mission of making storing, using, and protecting that data astonishingly easy, and the updates I’ve shared today are a big step forward in ensuring we can do so for the long haul. So, in closing, I’ll say thank you for entrusting us with your precious data—we’re honored to serve you.
FAQ: B2 Cloud Storage
Am I affected by this B2 Cloud Storage pricing update?
Maybe. This update applies to B2 Cloud Storage pay-as-you-go customers—those who pay variable monthly amounts based on their actual consumption of the service—who have not entered into committed contracts for one or more years.
When will I, as an existing B2 Cloud Storage pay-as-you-go customer, see this update in my monthly bill?
The updated pricing is effective October 3, 2023, so you will see it applied starting from this date to bills sent after this date.
How does Backblaze measure monthly average storage and free egress?
Backblaze measures pay-as-you-go customers’ usage in byte hours. The monthly storage average is based on the byte hours. As of October 3, 2023, monthly egress up to three times your average is free; any monthly egress above this 3x average is priced at $0.01 per GB.
Will Backblaze continue to offer unlimited free egress to CDN and compute partners?
Yes. This change has no impact on the unlimited free egress that Backblaze offers through leading CDN and compute partners including Fastly, Cloudflare, CacheFly, bunny.net, and Vultr.
How can I switch from pay-as-you-go B2 Cloud Storage to a B2 Reserve annual capacity bundle plan?
B2 Reserve bundles start at 20TB. You can explore B2 Reserve with our Sales Team here to discuss making a switch.
Is Backblaze still much more affordable than other cloud providers like AWS?
Yes. Backblaze remains highly affordable compared to other cloud storage providers. The service also remains roughly one-fifth the cost of AWS S3 for the combination of hot storage and egress, with the exact difference varying based on usage. For example, if you store 10TB in the U.S. West and also egress 10% of it in a month, your pricing from Backblaze and AWS is as follows:
In this instance, Backblaze is 17% or about one-fifth the cost of AWS S3.
What sort of improvements do you plan alongside the increase in pricing?
Beyond including free egress for all customers, we have a number of other upgrades and improvements in the pipeline. We’ll be announcing them in the coming months, but they include improvements to the upload experience, features to expand use cases for application storage customers, new integrations, and more partnerships.
Is Backlaze making any other updates to B2 Cloud Storage pricing, such as adding a minimum storage duration fee?
No. This is the extent of the update effective October 3, 2023. We also continue to believe that minimum storage duration fees as levied by some vendors run counter to the interests of many customers.
When was your last price increase?
This is the only price increase we have had since we launched B2 Cloud Storage in 2015.
FAQ: Computer Backup
What are the new prices?
Monthly licenses will be $9, yearly licenses will be $99, and two-year licenses will be $189. One Year Extended Version History will be available for free to those who wish to enable it. The $2 per month charge for Forever Version History will be removed while the incremental rate for when a file has been changed, modified, or deleted over a year ago will be $0.006/GB/month.
When are prices changing?
October 3, 2023 at 00:00 UTC is when the price increase will go into effect for new purchases and renewals. Existing contracts and licenses will be honored for their duration, and any prorated purchases after that time will be prorated at the new rate.
How does Extended Version History work?
Extended Version History allows you to “go back in time” further to retrieve earlier versions of your data. By default that setting is set to 30 days. With this update, you can choose to keep versions up to one year old for free.
What is a version?
When an individual file is changed, updated, edited, or deleted, without the file name changing, a new version is created.
When will the One Year Extended Version History option be included with my license?
On October 3, 2023, we’ll be removing the charge for selecting One Year Extended Version History. Any changes made to that setting ahead of that date will result in a prorated charge to the payment method on file.
I do not have One Year Extended Version History. Do I need to do anything to get it?
Yes. We will not be changing anyone’s settings on their behalf, so please see below for instructions on how to change your version history settings to one year. Note: making changes to this setting before October 3 will result in a prorated charge, as noted above.
How do I add One Year Extended Version History to my account or to my Group’s backups?
For individual Backblaze users: simply log in to your Backblaze account and navigate to the Overview page. From there you’ll see a list of all your computers and their selected Version History. To make a change, press the Update button next to the computer you wish to add One Year Extended Version History for.
For Group admins: simply log in to your Backblaze account and navigate to the Groups Management page. From there, you’ll see a list of all of the Groups you manage and their selected Version History. To make a change, press the Update button next to the Group you wish to enable One Year Extended Version History for, and all computers within it will be enabled.
Can I still use Forever Version History?
Yes. Forever Version History is still available. The prior $2 per month charge will be removed, and only files changed, deleted, or modified over a year ago will be charged at the incremental $0.006/GB/month.
I already have One Year Extended Version History on my account. Will my price go up?
It depends on your payment plan. If you are on a monthly plan with One Year Extended Version History, you will not see an increase. However, anyone on a yearly plan will see an increase from $94 to $99, and for two-year licenses, your price will increase from $178 to $189.
You probably invested in a network attached storage (NAS) device to centralize your storage, manage data more efficiently, and implement on-site backups. So, keeping that data safe is important to you. Unfortunately, as NAS devices have risen in popularity, cybercriminals have taken notice.
Recent high-profile ransomware campaigns have targeted vast numbers of NAS devices worldwide. These malicious attacks can lock away users’ NAS data, holding it hostage until a ransom is paid—or the user risks losing all their data.
If you are a NAS user, learning how to secure your NAS device against ransomware attacks is critical if you want to protect your data. In this guide, you’ll learn why NAS devices are attractive targets for ransomware and how to safeguard your NAS device from ransomware attacks. Let’s get started.
What Is Ransomware?
To begin, let’s quickly understand what ransomware actually is. Ransomware is a type of malicious software or malware that infiltrates systems and encrypts files. Upon successful infection, ransomware denies users access to their files or systems, effectively holding data hostage.
Its name derives from its primary purpose—to demand a “ransom” from the victim in exchange for restoring access to their data. Ransomware actors often threaten to delete, sell, or leak data if the ransom is not paid.
Ransomware threat messages often imitate law enforcement agencies, claiming that the user violated laws and must pay a fine. Other times, it’s a blunt threat—pay or lose your data forever. This manipulative strategy preys on fears and urgency, often pressuring the unprepared victims into paying the ransom.
The consequences of a ransomware attack can be severe. The most immediate impact is data loss, which can be catastrophic if the encrypted files contain sensitive or critical information. There’s also the financial loss from the ransom payment itself which can range from a few hundred dollars to several million dollars.
Moreover, an attack can cause significant operational downtime, with systems unavailable while the malware is removed and data is restored. For businesses, especially the unprepared, the downtime can be disastrous, leading to substantial revenue loss.
Cybersecurity Ventures expects that by 2031, businesses will fall victim to a ransomware attack every other second. Source.
However, the damage doesn’t stop there. The reputational damage caused by a ransomware attack can make customers, partners, and stakeholders lose trust in a business that falls victim to such an attack, especially if it results in a data breach.
As you can see, ransomware is not just malicious code that disrupts your business, it can cause significant harm on multiple fronts. Therefore, it’s important to understand the basics of ransomware as the first step in building a robust defense strategy for your NAS device.
Types of Ransomware
While the modus operandi of ransomware—to deny access to users’ data and demand ransom—remains relatively constant, there are multiple ransomware variants, each with unique characteristics.
Some of the most common types of ransomware include:
Locker Ransomware
Locker ransomware takes an all-or-nothing approach. It locks users out of their entire system, preventing them from accessing any files, applications, or even the operating system itself.
The only thing the users can access is a ransomware note, demanding payment in exchange for restoring access to their system.
Crypto Ransomware
As its name suggests, crypto ransomware encrypts the users’ files and makes them inaccessible. This type of ransomware does not lock the entire system, but rather targets specific file types such as documents, spreadsheets, and multimedia files. The victims can still use their system but cannot access or open the encrypted files without the encryption key.
Ransomware as a Service (RaaS)
RaaS represents a new business model in the dark world of cybercrime. It is essentially a cloud-based platform where ransomware developers sell or rent their ransomware codes to other cybercriminals, who then distribute and manage the ransomware attacks. The ransomware developers receive a cut of the ransom payments.
Leakware
Leakware steals sensitive or confidential information and threatens to publicize them if ransom is not paid. This type of ransomware is particularly damaging as even if the ransom is paid and the data is not leaked, the mere fact that the data was accessed can have significant legal and reputational implications.
Only 4% of victims who paid ransoms actually got all of their data back. Source.
Scareware
Scareware uses social engineering to trick victims into believing that their system is infected with viruses or other malware. They scare people into visiting spoofed or infected websites or downloading malicious software (malware). While not as directly damaging as other forms of ransomware, scareware can be used as the gateway to a more intricate cyberattack and may not be an attack in and of itself.
Can Ransomware Attack NAS?
Yes, ransomware can and frequently does target NAS devices. These storage solutions, while highly effective and efficient, have certain characteristics that make them attractive to cybercriminals.
Let’s explore some of these reasons in more detail below.
Centralized Storage
NAS devices act as centralized storage locations with all data stored in one place. This makes them an attractive target for ransomware attacks. By infiltrating a single NAS device, bad actors can gain access to a significant amount of company data, maximizing the impact of their attack and the potential ransom.
Security Vulnerabilities
Unlike traditional PCs or servers, NAS devices often lack robust security measures. Most NAS systems may not have an antivirus installed, leaving them exposed to various forms of malware including ransomware. Additionally, outdated firmware can further weaken the device’s defenses, offering potential loopholes for attackers to exploit.
Always Online
NAS devices are designed to be continuously online, allowing for convenient and seamless data access. However, this also means they are constantly exposed to the internet, making them a target for online threats around the clock.
Default Configuration Settings
NAS devices, like many other hardware devices, often come with default configurations that prioritize ease of access over security. For example, they may have simple, easy-to-guess default passwords or open access permissions for all users. Not changing these default settings can leave the devices vulnerable to attacks.
Risk Factors: The Human Element
NAS devices are an easy-to-use, accessible way to expand on-site storage and manage data, making them attractive for people without an IT background to use. However, novice users, and even many of your smartest power users, may not know to follow key best practices to prevent ransomware. As humans, all of us are vulnerable to error. In addition to NAS devices having some unique characteristics that make them prime targets for cybercriminals, you can’t discount the human element in ransomware protection. Understanding the following risks can help you shore up your defenses:
Lack of User Awareness
There is often a lack of awareness among NAS users about the potential security risks associated with these devices. Most users may not realize the importance of regularly updating their NAS systems or implementing security measures. This can result in NAS devices being unprotected, making them easy prey for ransomware attacks.
Insufficient Backup Practices
While NAS devices provide local data storage, it has to be noted that they are not a full 3-2-1 backup solution. Data on NAS devices needs to be backed up off-site to protect against hardware failures, theft, natural disasters, and ransomware attacks. If users don’t have an off-site backup, they risk losing all their data or paying a huge ransom to get access to their NAS data.
Lack of Regular Audits
Conducting regular security checks and audits can help identify and rectify any potential vulnerabilities. But, most NAS users take regular security audits as an afterthought and let security gaps go unnoticed and unaddressed.
Uncontrolled User Access
In some organizations, NAS devices may be accessed by numerous employees, some of whom may not be trained in security best practices. This can increase the chances of ransomware attacks via tactics like phishing emails.
Up to 70% of phishing emails are opened by the recipient. Source.
Neglected Software Updates
NAS device manufacturers often release software updates that include patches for security vulnerabilities. If users neglect to regularly update the software on their NAS devices, they can leave the devices exposed to ransomware attacks that exploit those vulnerabilities.
How Do I Protect My NAS From Ransomware?
Now that you understand the NAS devices vulnerabilities and threats that expose them to ransomware attacks, let’s take a look at some of the practical measures that you can take to protect your NAS from these attacks.
Update regularly: One of the most straightforward yet effective measures you can take is to keep your NAS devices’ applications up-to-date. This includes applying patches, firmware, and operating system updates as soon as they’re available and released by your NAS device manufacturer or backup application provider. These updates often contain security enhancements and fixes for vulnerabilities that could otherwise be exploited by ransomware.
Use strong credentials: Make sure all user accounts, especially admin accounts, are protected by strong, unique passwords. Strong credentials are a simple but effective way to avoid falling victim to brute force attacks that use a trial and error method to crack passwords.
Disable default admin accounts: Like we discussed above, most NAS devices come with default admin accounts with well-known usernames and passwords, making them easy targets for attackers. It’s a good idea to disable all these default accounts or change their credentials.
Limit access to NAS: Most businesses provide wide open access to all their users to access NAS data. However, chances are that not every user needs access to every file on your NAS. Limiting access based on user roles and responsibilities can minimize the potential impact in case of a ransomware attack.
Create different user access levels: Along the same lines of limiting access, consider creating different levels of user access. This can prevent a ransomware infection from spreading if a user with a lower level of access falls victim to an attack.
Block suspicious IP addresses: Consider utilizing network security tools to monitor and block IP addresses that have made multiple failed login attempts and/or seem suspicious. This can help prevent brute force attacks.
Implement a firewall and intrusion detection system: Firewalls can prevent unauthorized access to your NAS, while intrusion detection systems can alert you to any potential security breaches. Both can be crucial ways of defense against ransomware.
Adopt the 3-2-1 backup rule with Object Lock: Like we discussed above, NAS devices offer a centralized storage solution that is local, fast, and easy to share. However, NAS is not a backup solution as it doesn’t protect your data from theft, natural disasters, or hardware failures. Therefore, it’s essential to implement a 3-2-1 backup strategy, where three copies of your data is stored on two different types of storage with one copy stored off-site. This can ensure that you have a secure and uninfected backup even if your NAS is hit by ransomware. The Object Lock feature, available with cloud storage providers such as Backblaze, prevents data from being deleted, ensuring your backup remains intact even in the event of a ransomware attack.
The Role of Cybersecurity Training
While technical measures are a crucial part of NAS ransomware protection, they are only as effective as the people who use them. Human error is often cited as one of the leading causes of successful cyber-attacks, including ransomware.
This is where cybersecurity training comes in, playing an important role in helping individuals identify and avoid threats.
Studies have shown that in 93% of cases, an external attacker can breach an organizations network perimeter and gain access to local network resources. Source.
So, what kind of training can you do to help your staff avoid threats?
Identification training: Provide staff members with the knowledge and tools they need to recognize potential threats. This includes identifying suspicious emails, websites, or software, and understanding the dangers of clicking on unverified links or downloading unknown attachments, and also knowing how to handle and report a suspected threat when one arises.
Understanding human attack vendors: Cybercriminals often target individuals within an organization, exploiting common human weaknesses such as lack of awareness or curiosity. By understanding how these attacks work, employees can be better equipped to avoid falling victim to them.
Preventing attacks: Ultimately, the goal of cyber security training is to prevent attacks. By training staff on how to recognize and respond to potential threats, businesses can drastically reduce their risk of a successful ransomware attack. This not only helps the company’s data but also its reputation and financial well-being.
Also, it is important to remember that cybersecurity training should not be a one-time event. Cyber threats are constantly evolving, so regular training is necessary to ensure that staff members are aware of the latest threats and the best practices for dealing with them.
Protecting Your NAS Data From Threats
Ransomware is an ever evolving threat in our digital world and NAS devices are no exception. With the rising popularity of NAS devices among businesses, cybercriminals have been targeting NAS devices with high profile ransomware campaigns.
Having a comprehensive understanding of the basics of ransomware to recognize why NAS devices are attractive targets is the first step toward protecting your NAS devices from these attacks. By keeping systems and applications updated, enforcing robust credentials, limiting access, employing proactive network security measures, and backing up data, you can create a strong defense line against ransomware attacks.
Additionally, investing in regular cybersecurity training for all users can significantly decrease the risk of an attack being successful due to human error. Remember, cybersecurity is not a one-time effort but a continuous process of learning, adapting, and implementing best practices. Stay informed about the latest NAS ransomware types and tactics, maintain regular audits of your NAS devices, and continuously reevaluate and improve your security measures.
Every step you take towards better security not only protects your NAS data, but sends a strong message to cybercriminals and contributes towards a safer digital ecosystem for all.
Backblaze is happy to announce that Chris Opat has joined our team as senior vice president of cloud operations. Chris will oversee the strategy and operations of the Backblaze global cloud storage platform.
What Chris Brings to Backblaze
Chris expands the company’s leadership by bringing his impressive cloud and infrastructure knowledge with more than 25 years of industry experience.
Previously, Chris served as senior vice president leading platform engineering and operations at StackPath, a specialized provider in edge technology and content delivery. He also held leadership roles at CyrusOne, CompuCom, Cloudreach, and Bear Stearns/JPMorgan. Chris earned his Bachelor of Science degree in television and digital media production from Ithaca College.
Backblaze CEO, Gleb Budman, shared that Chris is a forward-thinking cloud leader with a proven track record of leading teams that are clever and bold in solving problems and creating best-in-class experiences for customers. His expertise and approach will be pivotal as more customers move to an open cloud ecosystem and will help advance Backblaze’s cloud strategy as we continue to grow.
Chris’ Role as SVP of Cloud Operations
As SVP of Cloud Operations, Chris oversees cloud strategy, platform engineering, and technology infrastructure, enabling Backblaze to further scale capacity and improve performance to meet larger-sized customers’ needs, as we continue to see success in moving up-market.
Chris says of his new role at Backblaze:
Backblaze’s vision and mission resonate with me. I’m proud to be joining a company that is supporting customers and advocating for an open cloud ecosystem. I’m looking forward to working with the amazing team at Backblaze as we continue to scale with our customers and accelerate growth.
This post was originally published in 2017 and updated in 2019 and 2023 to share the latest information on cloud storage tiering.
Temperature, specifically a range from cold to hot, is a common way to describe different levels of data storage. It’s possible these terms originated based on where data was historically stored. Hot data was stored close to the heat of the spinning drives and CPUs. Cold data was stored on drives or tape away from the warmer data center, likely tucked away on a shelf somewhere.
Today, they’re used to describe how easily you can access your data. Hot storage is for data you need fast or access frequently. Cold storage is typically used for data you rarely need. The terms are used by most data storage providers to describe their tiered storage plans. However, there are no industry standard definitions for what hot and cold mean, which makes comparing services across different storage providers challenging.
It’s a common misconception that hot storage means expensive storage and that cold storage means slower, less expensive storage. Today, we’ll explain why these terms may no longer be serving you when it comes to anticipating storage cost and performance.
Defining Hot Storage
Hot storage serves as the go-to destination for frequently accessed and mission-critical data that demands swift retrieval. Think of it as the fast lane of data storage, tailored for scenarios where time is of the essence. Industries relying on real-time data processing and rapid response times, such as video editing, web content, and application development, find hot storage to be indispensable.
To achieve the necessary rapid data access, hot storage is often housed in hybrid or tiered storage environments. The hotter the service, the more it embraces cutting-edge technologies, including the latest drives, fastest transport protocols, and geographical proximity to clients or multiple regions. However, the resource-intensive nature of hot storage warrants a premium, and leading cloud data storage providers like Microsoft’s Azure Hot Blobs and AWS S3 reflect this reality.
Data stored in the hottest tier might use solid-state drives (SSDs), which are optimized for lower latency and higher transactional rates compared to traditional hard drives. In other cases, hard disk drives are more suitable for environments where the drives are heavily accessed due to their higher durability standing up to intensive read/write cycles.
Regardless of the storage medium, hot data workloads necessitate fast and consistent response times, making them ideal for tasks like capturing telemetry data, messaging, and data transformation.
Defining Cold Storage
On the opposite end of the data storage spectrum lies cold storage, catering to information accessed infrequently and without the urgency of hot data. Cold storage houses data that might remain dormant for extended periods, months, years, decades, or maybe forever. Practical examples might include old projects or records mandated for financial, legal, HR, or other business record-keeping requirements.
Cold cloud storage systems prioritize durability and cost-effectiveness over real-time data manipulation capabilities. Services like Amazon Glacier and Google Coldline take this approach, offering slower retrieval and response times than their hot storage counterparts. Lower performing and less expensive storage environments, both on-premises and in the cloud, commonly host cold data.
Linear Tape Open (LTO or Tape) has historically been a popular storage medium for cold data, though manual retrieval from storage racks renders it relatively slow. To access data from LTO, the tapes must be physically retrieved from storage racks and mounted in a tape reading machine, making it one of the slowest, therefore coldest, methods of storing data.
While cold cloud storage systems generally boast lower overall costs than warm or hot storage, they may incur higher per-operation expenses. Accessing data from cold storage demands patience and thoughtful planning, as the response times are intentionally sluggish.
With the landscape of data storage continually evolving, the definition of cold storage has also expanded. In modern contexts, cold storage might describe completely offline data storage, wherein information resides outside the cloud and remains disconnected from any network. This isolation, also described as air gapped, is crucial for safeguarding sensitive data. However, today, data can be virtually air-gapped using technology like Object Lock.
Traditional Views of Cold and Hot Data Storage
Cold
Hot
Access Speed
Slow
Fast
Access Frequency
Seldom or Never
Frequent
Data Volume
Low
High
Storage Media
Slower drives, LTO, offline
Faster drives, durable drives, SSDs
Cost
Lower
Higher
What Is Hot Cloud Storage?
Today there are new players in data storage, who, through innovation and efficiency, are able to offer cloud storage at the cost of cold storage, but with the performance and availability of hot storage.
The concept of organizing data by temperature has long been employed by diversified cloud providers like Amazon, Microsoft, and Google to describe their tiered storage services and set pricing accordingly. But, today, in a cloud landscape defined by the open, multi-cloud internet, customers have come to realize the value and benefits they can get from moving away from those diversified providers.
A wave of independent cloud providers are disrupting the traditional notions of cloud storage temperatures, offering cloud storage that’s as cost-effective as cold storage, yet delivering the speed and availability associated with hot storage. If you’re familiar with Backblaze B2 Cloud Storage, you know where we’re going with this.
Backblaze B2 falls into this category. We can compete on price with LTO and other traditionally cold storage services, but can be used for applications that are usually reserved for hot storage, such as media management, workflow collaboration, websites, and data retrieval.
The newfound efficiency of this model has prompted customers to rethink their storage strategies, opting to migrate entirely from cumbersome cold storage and archival systems.
What Temperature Is Your Cloud Storage?
When it comes to choosing the right storage temperature for your cloud data, organizations must carefully consider their unique needs. Ensuring that storage costs align with actual requirements is key to maintaining a healthy bottom line. The ongoing evolution of cloud storage services, driven by efficiency, technology, and innovation, further amplifies the need for tailored storage solutions.
Still have questions that aren’t answered here? Join the discussion in the comments.
Are you confident that your backup strategy has you covered? If not, it’s time to confront the reality that your backup strategy might not be as strong as you think. And even if you’re feeling great about it, it can never hurt to poke holes in your strategy to see where you need to shore up your defenses.
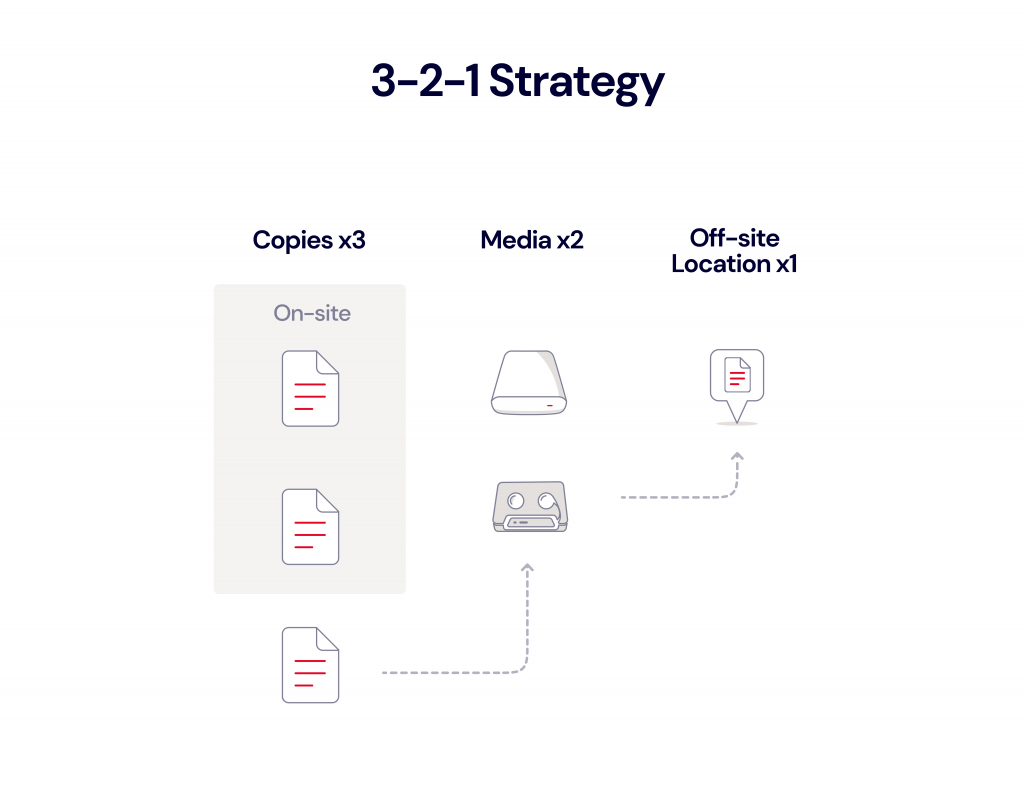
Whether you’re a small business owner wearing many hats (including the responsibility for backing up your company’s data) or a seasoned IT professional, you know that protecting your data is a top priority. The industry standard is the 3-2-1 backup strategy, which states you should have three copies of your data on two different kinds of media with at least one copy off-site or in the cloud. But a lot has changed since that standard was introduced.
In this post, we’ll identify several ways your 3-2-1 strategy (and your backups in general) could fail. These are common mistakes that even professional IT teams can make. While 3-2-1 is a great place to start, especially if you’re not currently following that approach, it can now be considered table stakes.
For larger businesses or any business wanting to fail proof its backups, read on to learn how you can plug the gaps in your 3-2-1 strategy and better secure your data from ransomware and other disasters.
Join the Webinar
There’s more to learn about how to shore up your data protection strategy. Join Backblaze on Thursday, August 10 at 10 a.m. PT/noon CT/5 p.m. UTC for a 30-minute webinar on “10 Common Data Protection Mistakes.”
Let’s start with a quick review of the 3-2-1 strategy.
The 3-2-1 Backup Strategy
A 3-2-1 strategy means having at least three total copies of your data, two of which are local but on different media, and at least one off-site copy or in the cloud. For instance, a business may keep a local copy of its data on a server at the main office, a second copy of its data on a NAS device in the same location, and a third copy of its data in the public cloud, such as Backblaze B2 Cloud Storage. Hence, there are three copies of its data with two local copies on different media (the server and NAS) and one copy stored off-site in the cloud.
The 3-2-1 rule originated in 2005 when Peter Krogh, a photographer, writer, and consultant, introduced it in his book, “The DAM Book: Digital Asset Management for Photographers.” As this rule was developed almost 20 years ago, you can imagine that it may be outdated in some regards. Consider that 2005 was the year YouTube was founded. Let’s face it, a lot has changed since 2005, and today the 3-2-1 strategy is just the starting point. In fact, even if you’re faithfully following the 3-2-1 rule, there may still be some gaps in your data protection strategy.
While backups to external hard drives, tape, and other recordable media (CDs, DVDs, and SD cards) were common two decades ago, those modalities are now considered legacy storage. The public cloud was a relatively new innovation in 2005, so, at first, 3-2-1 did not even consider the possibilities of cloud storage.
Arguably, the entire concept of “media” in 3-2-1 (as in having two local copies of your data on two different kinds of media) may not make sense in today’s modern IT environment. And, while an on-premises copy of your data typically offers the fastest Recovery Time Objective (RTO), having two local copies of your data will not protect against the multitude of potential natural disasters like fire, floods, tornados, and earthquakes.
The “2” part of the 3-2-1 equation may make sense for consumers and sole proprietors (e.g., photographers, graphic designers, etc.) who are prone to hardware failure and for whom having a second copy of data on a NAS device or external hard drive is an easy solution, but enterprises have more complex infrastructures.
Enterprises may be better served by having more than one off-site copy, in case of an on-premises data disaster. This can be easily automated with a cloud replication tool which allows you to store your data in different regions. (Backblaze offers Cloud Replication for this purpose.) Replicating your data across regions provides geographical separation from your production environment and added redundancy. The bottom line is that 3-2-1 is a good starting point for configuring your backup strategy, but it should not be taken as a one-size-fits-all approach.
The 3-2-1-1-0 Strategy
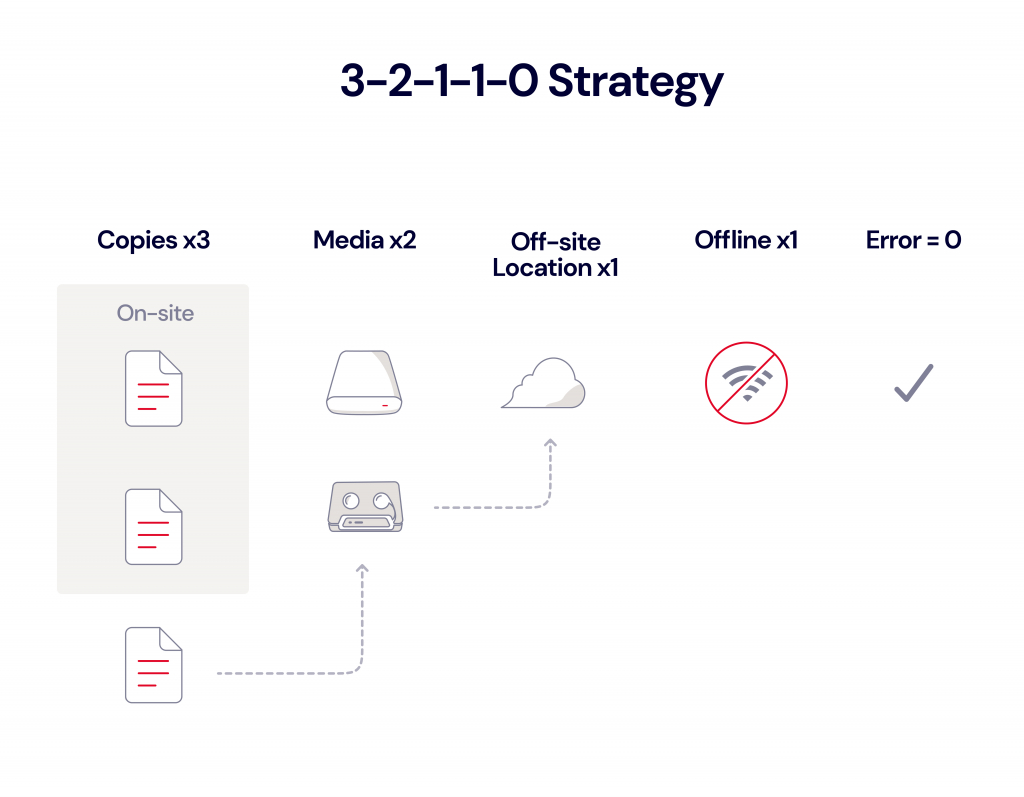
Some companies in the data protection space, like Veeam, have updated 3-2-1 with the 3-2-1-1-0 approach. This particular definition stipulates that you:
Maintain at least three copies of business data.
Store data on at least two different types of storage media.
Keep one copy of the backups in an off-site location.
Keep one copy of the media offline or air gapped.
Ensure all recoverability solutions have zero errors.
The 3-2-1-1-0 approach addresses two important weaknesses of 3-2-1. First, 3-2-1 doesn’t address the prevalence of ransomware. Even if you follow 3-2-1 with fidelity, your data could still be vulnerable to a ransomware attack. The 3-2-1-1-0 rule covers this by requiring one copy to be offline or air gapped. With Object Lock, your data can be made immutable, which is considered a virtual air gap, thus fulfilling the 3-2-1-1-0 rule.
Second, 3-2-1 does not consider disaster recovery (DR) needs. While backups are one part of your disaster recovery plan, your DR plan needs to consider many more factors. The “0” in 3-2-1-1-0 captures an important aspect of DR planning, which is that you must test your backups and ensure you can recover from them without error. Ultimately, you should architect your backup strategy to support your DR plan and the potential need for a recovery, rather than trying to abide by any particular backup rule.
Additional Gaps in Your Backup Strategy
As you can tell by now, there are many shades of gray when it comes to 3-2-1, and these varying interpretations can create areas of weakness in a business’ data protection plan. Review your own plan for the following seven common mistakes and close the gaps in your strategy by implementing the suggested best practices.
1. Using Sync Functionality Instead of Backing Up
You may be following 3-2-1, but if copies of your data are stored on a sync service like Google Drive, Dropbox, or OneDrive, you’re not fully protected. Syncing your data does not allow you to recover from previous versions with the level of granularity that a backup offers.
Best Practice: Instead, ensure you have three copies of your data protected by true backup functionality.
2. Counting Production Data as a Backup
Some interpret the production data to be one of the three copies of data or one of the two different media types.
Best Practice: It’s open to interpretation, but you may want to consider having three copies of data in addition to your production data for the best protection.
3. Using a Storage Appliance That’s Vulnerable to Ransomware
Many on-premises storage systems now support immutability, so it’s a good time to reevaluate your local storage.
Best Practice: New features in popular backup software like Veeam even enable NAS devices to be protected from ransomware. Learn more about Veeam support for NAS immutability and how to orchestrate end-to-end immutability for impenetrable backups.
4. Not Backing Up Your SaaS Data
It’s a mistake to think your Microsoft 365, Google Workspace, and other software as a service (SaaS) data is protected because it’s already hosted in the cloud. SaaS providers operate under a “shared responsibility model,” meaning they may not back up your data as often as you’d like or provide effective means to recovery.
Best Practice: Be sure to back up your SaaS data to the cloud to ensure complete coverage of the 3-2-1 rule.
5. Relying On Off-Site Legacy Storage
It’s always a good idea to have at least one copy of your data on-site for the fastest RTO. But if you’re relying on legacy storage, like tape, to fulfill the off-site requirement of the 3-2-1 strategy, you probably know how expensive and time-consuming it can be. And sometimes that expense and timesuck means your off-site backups are not updated as often as they should be, which leads to mistakes.
Best Practice: Replace your off-site storage with cloud storage to modernize your architecture and prevent gaps in your backups. Backblaze B2 is one-fifth of the cost of AWS, so it’s easily affordable to migrate off tape and other legacy storage systems.
6. No Plan for Affected Infrastructure
Faithfully following 3-2-1 will get you nowhere if you don’t have the infrastructure to restore your backups. If your infrastructure is destroyed or disrupted, you need a way to ensure business continuity in the face of data disaster.
Best Practice: Be sure your disaster recovery plan outlines how you will access your DR documentation and implement the plan even if your environment is down. Using a tool like Cloud Instant Business Recovery (Cloud IBR), which offers an on-demand, automated solution that allows Veeam users to stand up bare metal servers in the cloud, allows you to immediately begin recovering data while rebuilding infrastructure.
7. Keeping Your Off-Site Copy Down the Street
The 3-2-1 policy states that one copy of your data be kept off-site, and some companies maintain a DR site for that exact purpose. However, if your DR facility is in the same local area as your main office, you have a big gap in your data protection strategy.
Best Practice: Ideally, you should have an off-site copy of your data stored in a public cloud data center far from your data production site, to protect against regional natural disasters.
Telco Adopts Cloud for Geographic Separation
AcenTek’s existing storage scheme covered the 3-2-1 basics, but their off-site copy was no further away than their own data center. In the case of a large natural disaster, their one off-site copy could be vulnerable to destruction, leaving them without a path to recovery. With Backblaze B2, AcenTek has an additional layer of resilience for its backup data by storing it in a secure, immutable cloud storage platform across the country from their headquarters in Minnesota.
Modernize Your Backup Strategy
The 3-2-1 strategy is a great starting point for small businesses that need to develop a backup plan, but larger mid-market and enterprise organizations must think about business continuity more holistically.
Backblaze B2 Cloud Storage makes it easy to modernize your backup strategy by sending data backups and archives straight to the cloud—without the expense and complexity of many public cloud services.
At one-fifth of the price of AWS, Backblaze B2 is an affordable, time-saving alternative to the hyperscalers, LTO, and traditional DR sites. Get started today or contact Sales for more information on Backblaze B2 Reserve, Backblaze’s all-inclusive capacity-based pricing that includes premium support and no egress fees. The intricacies of operations, data management, and potential risks demand a more advanced approach to ensure uninterrupted operations. By leveraging cloud storage, you can create a robust, cost-effective, and flexible backup strategy that you can easily customize to your business needs.
Interested in learning more about backup, business continuity, and disaster recovery best practices? Check out the free Backblaze resources below.
At the end of Q2 2023, Backblaze was monitoring 245,757 hard drives and SSDs in our data centers around the world. Of that number, 4,460 are boot drives, with 3,144 being SSDs and 1,316 being HDDs. The failure rates for the SSDs are analyzed in the SSD Edition: 2022 Drive Stats review.
Today, we’ll focus on the 241,297 data drives under management as we review their quarterly and lifetime failure rates as of the end of Q2 2023. Along the way, we’ll share our observations and insights on the data presented, tell you about some additional data fields we are now including and more.
Q2 2023 Hard Drive Failure Rates
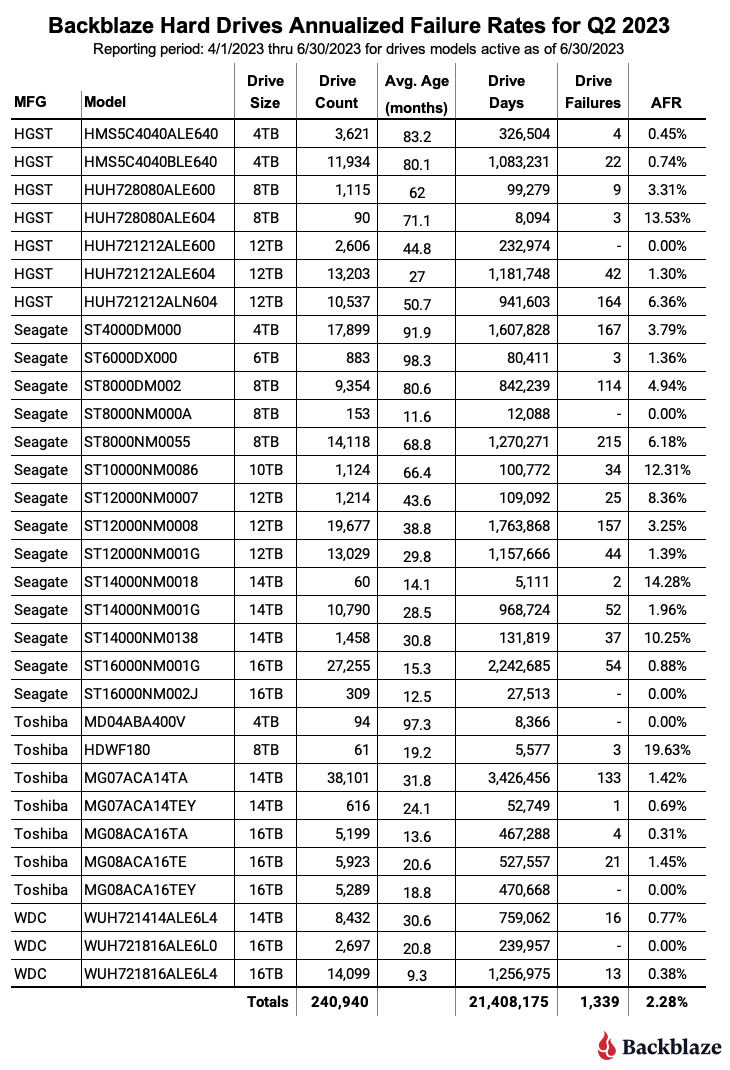
At the end of Q2 2023, we were managing 241,297 hard drives used to store data. For our review, we removed 357 drives from consideration as they were used for testing purposes or drive models which did not have at least 60 drives. This leaves us with 240,940 hard drives grouped into 31 different models. The table below reviews the annualized failure rate (AFR) for those drive models for Q2 2023.
Notes and Observations on the Q2 2023 Drive Stats
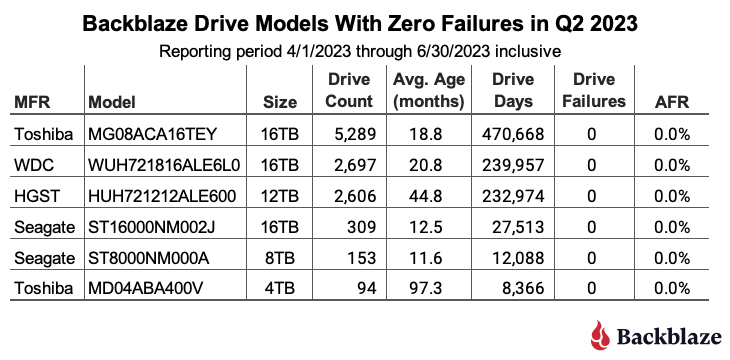
Zero Failures: There were six drive models with zero failures in Q2 2023 as shown in the table below.
The table is sorted by the number of drive days each model accumulated during the quarter. In general a drive model should have at least 50,000 drive days in the quarter to be statistically relevant. The top three drives all meet that criteria, and having zero failures in a quarter is not surprising given the lifetime AFR for the three drives ranges from 0.13% to 0.45%. None of the bottom three drives has accumulated 50,000 drive days in the quarter, but the two Seagate drives are off to a good start. And, it is always good to see the 4TB Toshiba (model: MD04ABA400V), with eight plus years of service, post zero failures for the quarter.
The Oldest Drive? The drive model with the oldest average age is still the 6TB Seagate (model: ST6000DX000) at 98.3 months (8.2 years), with the oldest drive of this cohort being 104 months (8.7 years) old.
The oldest operational data drive in the fleet is a 4TB Seagate (model: ST4000DM000) at 105.2 months (8.8 years). That is quite impressive, especially in a data center environment, but the winner for the oldest operational drive in our fleet is actually a boot drive: a WDC 500GB drive (model: WD5000BPKT) with 122 months (10.2 years) of continuous service.
Upward AFR: The AFR for Q2 2023 was 2.28%, up from 1.54% in Q1 2023. While quarterly AFR numbers can be volatile, they can also be useful in identifying trends which need further investigation. In this case, the rise was expected as the age of our fleet continues to increase. But was that the real reason?
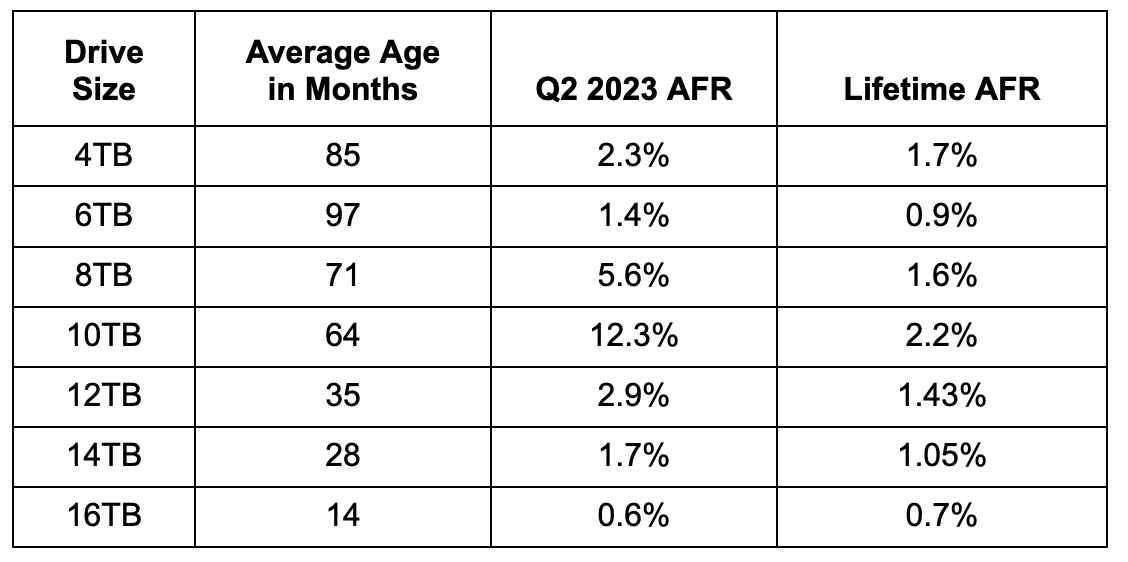
Digging in, we start with the annualized failure rates and average age of our drives grouped by drive size, as shown in the table below.
For our purpose, we’ll define a drive as old when it is five years old or more. Why? That’s the warranty period of the drives we are purchasing today. Of course, the 4TB and 6TB drives, and some of the 8TB drives, came with only two year warranties, but for consistency we’ll stick with five years as the point at which we label a drive as “old”.
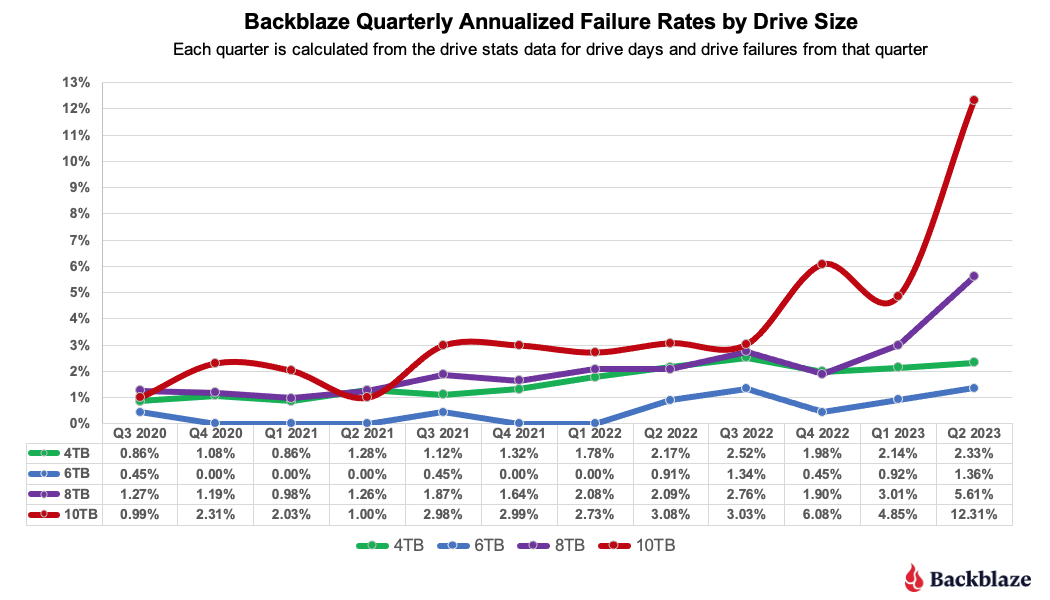
Using our definition for old drives eliminates the 12TB, 14TB and 16TB drives. This leaves us with the chart below of the Quarterly AFR over the last three years for each cohort of older drives, the 4TB, 6TB, 8TB, and 10TB models.
Interestingly, the oldest drives, the 4TB and 6TB drives, are holding their own. Yes, there has been an increase over the last year or so, but given their age, they are doing well.
On the other hand, the 8TB and 10TB drives, with an average of five and six years of service respectively, require further attention. We’ll look at the lifetime data later on in this report to see if our conclusions are justified.
What’s New in the Drive Stats Data?
For the past 10 years, we’ve been capturing and storing the drive stats data and since 2015 we’ve open sourced the data files that we used to create the Drive Stats reports. From time to time, new SMART attribute pairs have been added to the schema as we install new drive models which report new sets of SMART attributes. This quarter we decided to capture and store some additional data fields about the drives and the environment they operate in, and we’ve added them to the publicly available Drive Stats files that we publish each quarter.
The New Data Fields
Beginning with the Q2 2023 Drive Stats data, there are three new data fields populated in each drive record.
Vault_id: All data drives are members of a Backblaze Vault. Each vault consists of either 900 or 1,200 hard drives divided evenly across 20 storage servers. The vault is a numeric value starting at 1,000.
Pod_id: There are 20 storage servers in each Backblaze Vault. The Pod_id is a numeric field with values from 0 to 19 assigned to one of the 20 storage servers.
Is_legacy_format: Currently 0, but will be useful over the coming quarters as more fields are added.
The new schema is as follows:
date
serial_number
model
capacity_bytes
failure
vault_id
pod_id
is_legacy_format
smart_1_normalized
smart_1_raw
Remaining SMART value pairs (as reported by each drive model)
Occasionally, our readers would ask if we had any additional information we could provide with regards to where a drive lived, and, more importantly, where it died. The newly-added data fields above are part of the internal drive data we collect each day, but they were not included in the Drive Stats data that we use to create the Drive Stats reports. With the help of David from our Infrastructure Software team, these fields will now be available in the Drive Stats data.
How Can We Use the Vault and Pod Information?
First a caveat: We have exactly one quarter’s worth of this new data. While it was tempting to create charts and tables, we want to see a couple of quarters worth of data to understand it better. Look for an initial analysis later on in the year.
That said, what this data gives us is the storage server and the vault of every drive. Working backwards, we should be able to ask questions like: “Are certain storage servers more prone to drive failure?” or, “Do certain drive models work better or worse in certain storage servers?” In addition, we hope to add data elements like storage server type and data center to the mix in order to provide additional insights into our multi-exabyte cloud storage platform.
Over the years, we have leveraged our Drive Stats data internally to improve our operational efficiency and durability. Providing these new data elements to everyone via our Drive Stats reports and data downloads is just the right thing to do.
There’s a New Drive in Town
If you do decide to download our Drive Stats data for Q2 2023, there’s a surprise inside—a new drive model. There are only four of these drives, so they’d be easy to miss, and they are not listed on any of the tables and charts we publish as they are considered “test” drives at the moment. But, if you are looking at the data, search for model “WDC WUH722222ALE6L4” and you’ll find our newly installed 22TB WDC drives. They went into testing in late Q2 and are being put through their paces as we speak. Stay tuned. (Psst, as of 7/28, none had failed.)
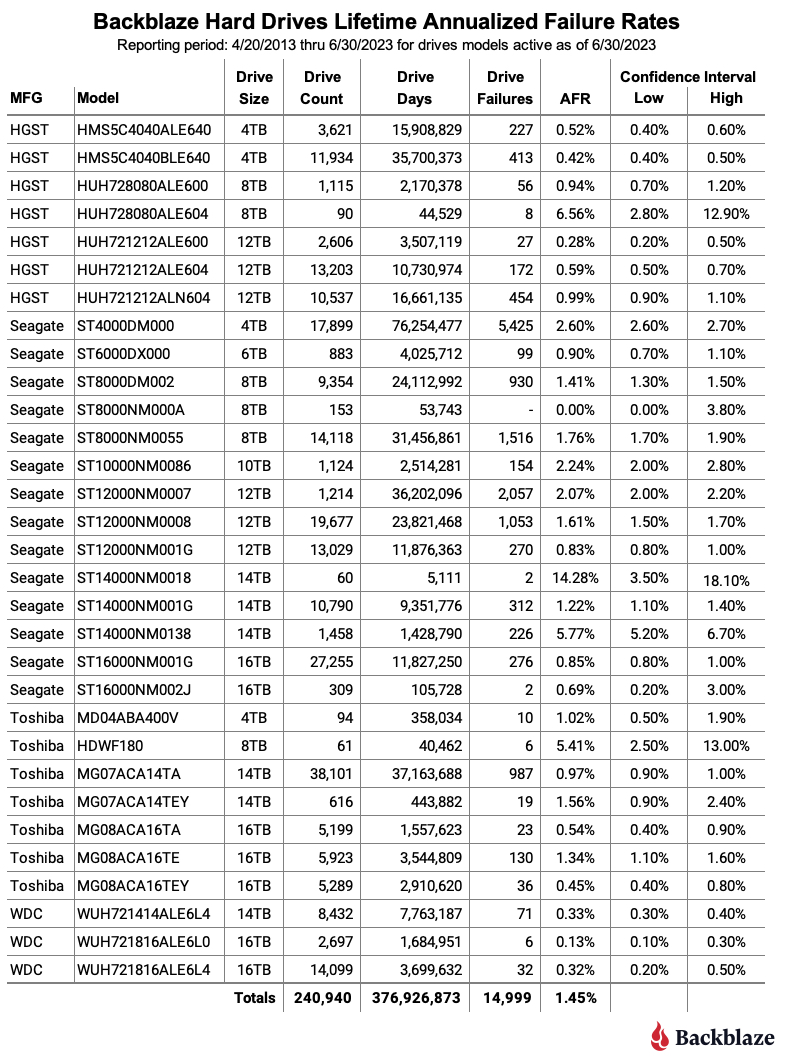
Lifetime Hard Drive Failure Rates
As of June 30, 2023, we were tracking 241,297 hard drives used to store customer data. For our lifetime analysis, we removed 357 drives that were only used for testing purposes or did not have at least 60 drives represented in the full dataset. This leaves us with 240,940 hard drives grouped into 31 different models to analyze for the lifetime table below.
Notes and Observations About the Lifetime Stats
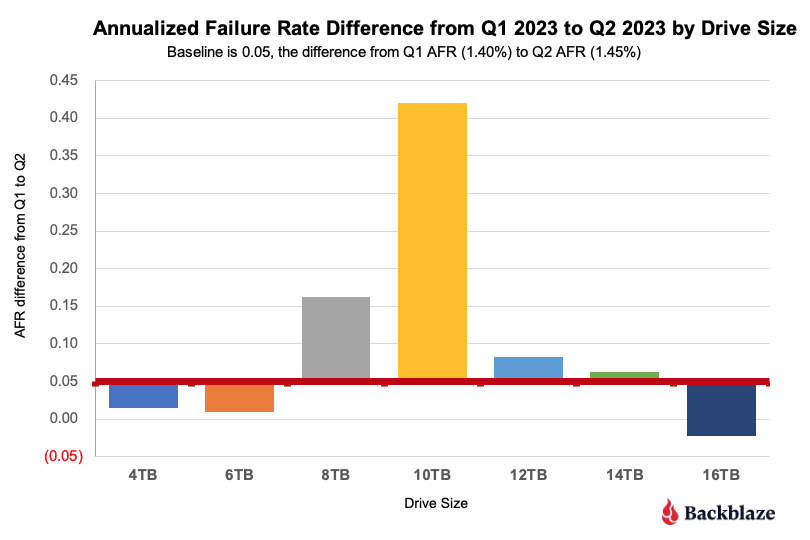
The Lifetime AFR also rises. The lifetime annualized failure rate for all the drives listed above is 1.45%. That is an increase of 0.05% from the previous quarter of 1.40%. Earlier in this report by examining the Q2 2023 data, we identified the 8TB and 10TB drives as primary suspects in the increasing rate. Let’s see if we can confirm that by examining the change in the lifetime AFR rates of the different drives grouped by size.
The red line is our baseline as it is the difference from Q1 to Q2 (0.05%) of the lifetime AFR for all drives. Drives above the red line support the increase, drives below the line subtract from the increase. The primary drives (by size) which are “driving” the increased lifetime annualized failure rate are the 8TB and 10TB drives. This confirms what we found earlier. Given there are relatively few 10TB drives (1,124) versus 8TB drives (24,891), let’s dig deeper into the 8TB drives models.
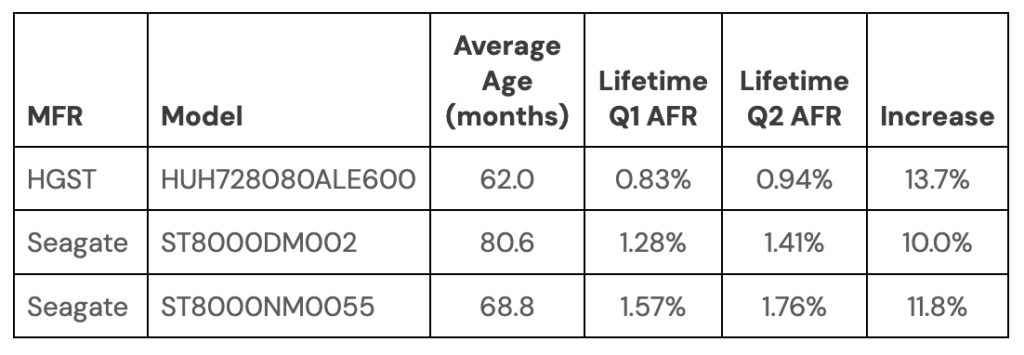
The Lifetime AFR for all 8TB drives jumped from 1.42% in Q1 to 1.59% in Q2. An increase of 12%. There are six 8TB drive models in operation, but three of these models comprise 99.5% of the drive failures for the 8TB drive cohort, so we’ll focus on them. They are listed below.
For all three models, the increase of the lifetime annualized failure rate from Q1 to Q2 is 10% or more which is statistically similar to the 12% increase for all of the 8TB drive models. If you had to select one drive model to focus on for migration, any of the three would be a good candidate. But, the Seagate drives, model ST8000DM002, are on average nearly a year older than the other drive models in question.
Not quite a lifetime? The table above analyzes data for the period of April 20, 2013 through June 30, 2023, or 10 years, 2 months and 10 days. As noted earlier, the oldest drive we have is 10 years and 2 months old, give or take a day or two. It would seem we need to change our table header, but not quite yet. A drive that was installed anytime in Q2 2013 and is still operational today would report drive days as part of the lifetime data for that model. Once all the drives installed in Q2 2013 are gone, we can change the start date on our tables and charts accordingly.
A Word About Drive Failure
Are we worried about the increase in drive failure rates? Of course we’d like to see them lower, but the inescapable reality of the cloud storage business is that drives fail. Over the years, we have seen a wide range of failure rates across different manufacturers, drive models, and drive sizes. If you are not prepared for that, you will fail. As part of our preparation, we use our drive stats data as one of the many inputs into understanding our environment so we can adjust when and as we need.
So, are we worried about the increase in drive failure rates? No, but we are not arrogant either. We’ll continue to monitor our systems, take action where needed, and share what we can with you along the way.
The Hard Drive Stats Data
The complete data set used to create the information used in this review is available on our Hard Drive Stats Data webpage. You can download and use this data for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, and 3) you do not sell this data to anyone; it is free.
If you want the tables and charts used in this report, you can download the .zip file from Backblaze B2 Cloud Storage which contains an MS Excel spreadsheet with a tab for each of the tables or charts..
Good luck and let us know if you find anything interesting.
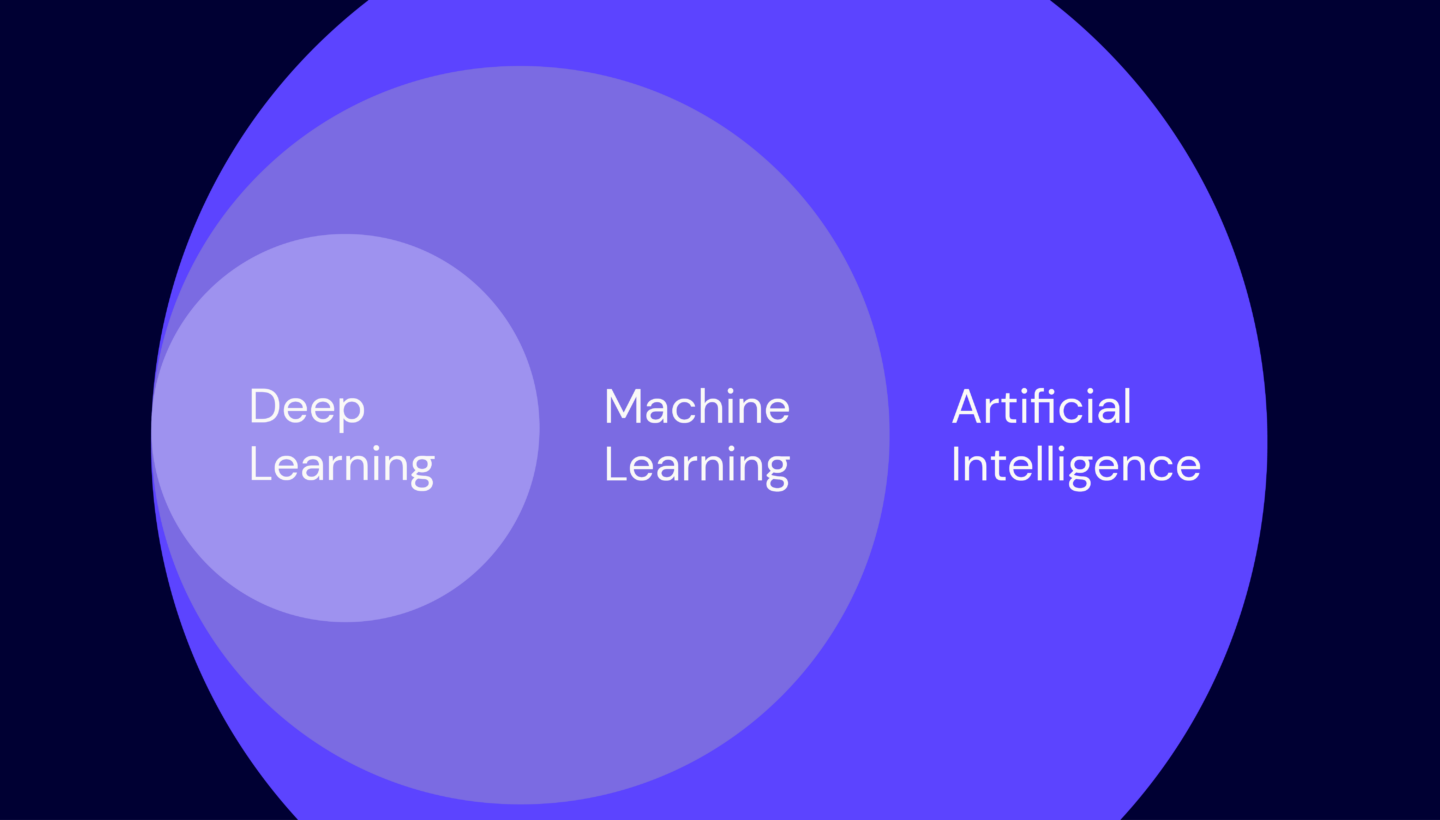
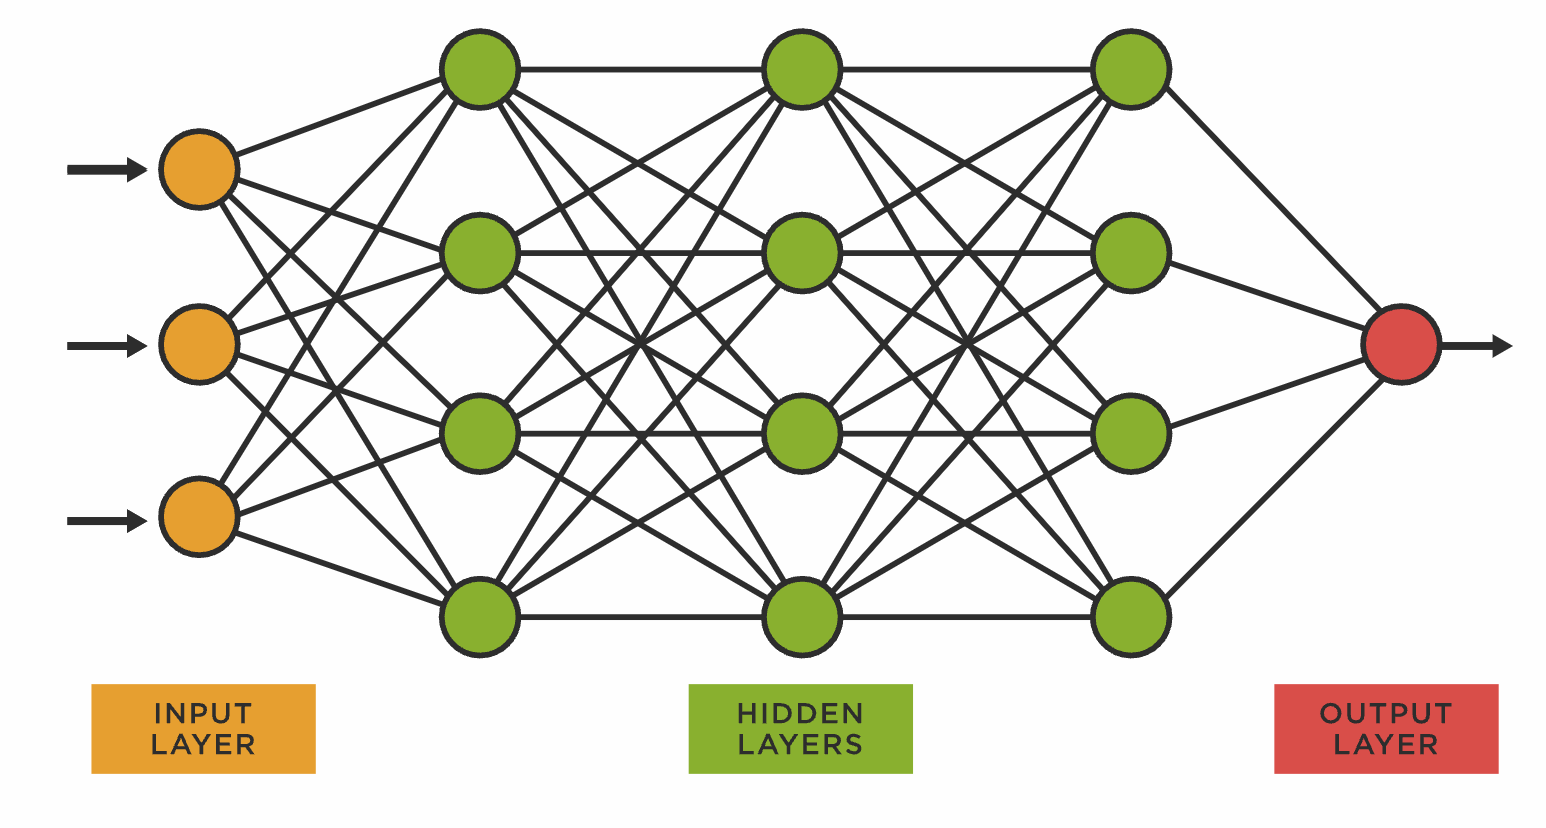
It’s no secret that artificial intelligence (AI) is driving innovation, particularly when it comes to processing data at scale. Machine learning (ML) and deep learning (DL) algorithms, designed to solve complex problems and self-learn over time, are exploding the possibilities of what computers are capable of.
It’s no secret that artificial intelligence (AI) is driving innovation, particularly when it comes to processing data at scale. Machine learning (ML) and deep learning (DL) algorithms, designed to solve complex problems and self-learn over time, are exploding the possibilities of what computers are capable of.
As the problems we ask computers to solve get more complex, there’s also an unavoidable, explosive growth in the number of processes they run. This growth has led to the rise of specialized processors and a whole host of new acronyms.
Joining the ranks of central processing units (CPUs), which you may already be familiar with, are neural processing units (NPUs), graphics processing units (GPUs), and tensile processing units (TPUs).
So, let’s dig in to understand how some of these specialized processors work, and how they’re different from each other. If you’re still with me after that, stick around for an IT history lesson. I’ll get into some of the more technical concepts about the combination of hardware and software developments in the last 100 or so years.
Central Processing Unit (CPU): The OG
Think of the CPU as the general of your computer. There are two main parts of a CPU, an arithmetic-logic unit (ALU) and a control unit. An ALU allows arithmetic (add, subtract, etc.) and logic (AND, OR, NOT, etc.) operations to be carried out. The control unit controls the ALU, memory, and IO functions, which tells them how to respond to the program that’s just been read from the memory.
The best way to track what the CPU does is to think of it as an input/output flow. The CPU will take the request (input), access the memory of the computer for instructions on how to perform that task, delegate the execution to either its own ALUs or another specialized processor, take all that data back into its control unit, then take a single, unified action (output).
For a visual, this is the the circuitry map for an ALU from 1970:
From our good friends at Texas Instruments: the combinational logic circuitry of the 74181 integrated circuit, an early four-bit ALU. Image source.
But, more importantly, here’s a logic map about what a CPU does:
CPUs have gotten more powerful over the years as we’ve moved from single-core processors to multicore processors. Basically, there are several ALUs executing tasks that are being managed by the CPU’s control unit, and they perform tasks in parallel. That means that it works well in combination with specialized AI processors like GPUs.
The Rise of Specialized Processors
When a computer is given a task, the first thing the processor has to do is communicate with the memory, including program memory (ROM)—designed for more fixed tasks like startup—and data memory (RAM)—designed for things that change more often like loading applications, editing a document, and browsing the internet. The thing that allows these elements to talk is called the bus, and it can only access one of the two types of memory at one time.
In the past, processors ran more slowly than memory access, but that’s changed as processors have gotten more sophisticated. Now, when CPUs are asked to do a bunch of processes on large amounts of data, the CPU ends up waiting for memory access because of traffic on the bus. In addition to slower processing, it also uses a ton of energy. Folks in computing call this the Von Neumann bottleneck, and as compute tasks like those for AI have become more complex, we’ve had to work out ways to solve this problem.
One option is to create chips that are optimized to specific tasks. Specialized chips are designed to solve the processing difficulties machine learning algorithms present to CPUs. In the race to create the best AI processor, big players like Google, IBM, Microsoft, and Nvidia have solved this with specialized processors that can execute more logical queries (and thus more complex logic). They achieve this in a few different ways. So, let’s talk about what that looks like: What are GPUs, TPUs, and NPUs?
Graphics Processing Unit (GPU)
GPUs started out as specialized graphics processors and are often conflated with graphics cards (which have a bit more hardware to them). GPUs were designed to support massive amounts of parallel processing, and they work in tandem with CPUs, either fully integrated on the main motherboard, or, for heavier loads, on their own dedicated piece of hardware. They also use a ton of energy and thus generate heat.
GPUs have long been used in gaming, and it wasn’t until the 2000s that folks started using them for general computing—thanks to Nvidia. Nvidia certainly designs chips, of course, but they also introduced a proprietary platform called CUDA that allows programmers to have direct access to a GPU’s virtual instruction set and parallel computational elements. This means that you can set up compute kernels, or clusters of processors that work together and are ideally suited to specific tasks, without taxing the rest of your resources. Here’s a great diagram that shows the workflow:
This made GPUs wildly applicable for machine learning tasks, and they benefited from the fact that they leveraged existing, well-known processes. What we mean by that is: oftentimes when you’re researching solutions, the solution that wins is not always the “best” one based on pure execution. If you’re introducing something that has to (for example) fundamentally change consumer behavior, or that requires everyone to relearn a skill, you’re going to have resistance to adoption. So, GPUs playing nice with existing systems, programming languages, etc. aided wide adoption. They’re not quite plug-and-play, but you get the gist.
As time has gone on, there are now also open source platforms that support GPUs that are supported by heavy-hitting industry players (including Nvidia). The largest of these is OpenCL. And, folks have added tensor cores, which this article does a fabulous job of explaining.
Tensor Processing Unit (TPU)
Great news: the TL:DR of this acronym boils down to: It’s Google’s proprietary AI processor. They started using them in their own data centers in 2015, released them to the public in 2016, and there are some commercially available models. They run on ASICs (hard-etched chips I’ll talk more about later) and Google’s TensorFlow software.
Compared with GPUs, they’re specifically designed to have slightly lower precision, which makes sense given that this makes them more flexible to different types of workloads. I think Google themselves sum it up best:
If it’s raining outside, you probably don’t need to know exactly how many droplets of water are falling per second—you just wonder whether it’s raining lightly or heavily. Similarly, neural network predictions often don’t require the precision of floating point calculations with 32-bit or even 16-bit numbers. With some effort, you may be able to use 8-bit integers to calculate a neural network prediction and still maintain the appropriate level of accuracy.
GPUs, on the other hand, were originally designed for graphics processing and rendering, which relies on each point’s relationship to each other to create a readable image—if you have less accuracy in those points, you amplify that in their vectors, and then you end up with Playstation 2 Spyro instead of Playstation 4 Spyro.
Another important design choice that deviates from CPUs and GPUs is that TPUs are designed around a systolic array. Systolic arrays create a network of processors that are each computing a partial task, then sending it along to the next node until you reach the end of the line. Each node is usually fixed and identical, but the program that runs between them is programmable. It’s called a data processing unit (DPU).
Neural processing unit (NPU)
“NPU” is sometimes used as the category name for all specialized AI processors, but it’s more often specifically applied to those designed for mobile devices. Just for confusion’s sake, note that Samsung also refers to its proprietary chipsets as NPU.
NPUs contain all the necessary information to complete AI processing, and they run on a principle of synaptic weight. Synaptic weight is a term adapted from biology which describes the strength of connection between two neurons. Simply put, in our bodies if two neurons find themselves sharing information more often, the connection between them becomes literally stronger, making it easier for energy to pass between them. At the end of the day, that makes it easier for you to do something. (Wow, the science between habit forming makes a lot more sense now.) Many neural networks mimic this.
When we say AI algorithms learn, this is one of the ways—they track likely possibilities over time, and give more weight to that connected node. The impact is huge when it comes to power consumption. Parallel processing runs each task next to each other, but isn’t great at accounting for the completion of tasks, especially as your architecture scales and processing units might be more separate.
Quick Refresh: Neural Networks and Decision Making in Computers
As we discuss in AI 101, when you’re thinking about the process of making a decision, what you see is that you’re actually making many decisions in a series, and often the things you’re considering before you reach your final decision affect the eventual outcome. Since computers are designed on a strict binary, they’re not “naturally” suited to contextualizing information in order to make better decisions. Neural networks are the solution. They’re based on matrix math, and they look like this:
Basically, you’re asking a computer to have each potential decision check in with all the other possibilities, to weigh the outcome, and to learn from their own experience and sensory information. That all translates to more calculations being run at one time.
Recapping the Key Differences
That was a lot. Here’s a summary:
Functionality: GPUs were developed for graphics rendering, while TPUs and NPUs are purpose-built for AI/ML workloads.
Parallelism: GPUs are made for parallel processing, ideal for training complex neural networks. TPUs take this specialization further, focusing on tensor operations to achieve higher speeds and energy efficiencies.
Customization: TPUs and NPUs are more specialized and customized for AI tasks, while GPUs offer a more general-purpose approach suitable for various compute workloads.
Use Cases: GPUs are commonly used in data centers and workstations for AI research and training. TPUs are extensively utilized in Google’s cloud infrastructure, and NPUs are prevalent in AI-enabled devices like smartphones and Internet of Things (IoT) gadgets.
Availability: GPUs are widely available from various manufacturers and accessible to researchers, developers, and hobbyists. TPUs are exclusive to Google Cloud services, and NPUs are integrated into specific devices.
Do the Differences Matter?
The definitions of the different processors start to sound pretty similar after a while. A multicore processor combines multiple ALUs under a central control unit. A GPU combines more ALUs under a specialized processor. A TPU combines multiple compute nodes under a DPU, which is analogous to a CPU.
At the end of the day, there’s some nuance about the different design choices between processors, but their impact is truly seen at scale versus at the consumer level. Specialized processors can handle larger datasets more efficiently, which translates to faster processing using less electrical power (though our net power usage may go up as we use AI tools more).
It’s also important to note that these are new and changing terms in a new and changing landscape. Google’s TPU was announced in 2015, just eight years ago. I can’t count the amount of conversations I’ve had that end in a hyperbolic impression of what AI is going to do for/to the world, and that’s largely because people think that there’s no limit to what it is.
But, the innovations that make AI possible were created by real people. (Though, maybe AIs will start coding themselves, who knows.) And, chips that power AI are real things—a piece of silicon that comes from the ground and is processed in a lab. Wrapping our heads around what those physical realities are, what challenges we had to overcome, and how they were solved, can help us understand how we can use these tools more effectively—and do more cool stuff in the future.
Bonus Content: A Bit of a History of the Hardware
Which brings me to our history lesson. In order to more deeply understand our topic today, you have to know a little bit about how computers are physically built. The most fundamental language of computers is binary code, represented as a series of 0s and 1s. Those values correspond to whether a circuit is closed or open, respectively. When a circuit is closed, you cannot push power through it. When it’s open, you can. Transistors regulate current flow, generate electrical signals, and act as a switch or gate. You can connect lots of transistors with circuitry to create an integrated circuit chip.
The combination of open and closed patterns of transistors can be read by your computer. As you add more transistors, you’re able to express more and more numbers in binary code. You can see how this influences the basic foundations of computing in how we measure bits and bytes. Eight transistors store one byte of data: two possibilities for each of the eight transistors, and then every possible combination of those possibilities (2^8) = 256 possible combinations of open/closed gates (bits), so 8 bits = one byte, which can represent any number between 0 and 255.
Transistors combining to create logic. You need a bunch of these to run a program. Image source.
Improvements in reducing transistor size and increasing transistor density on a single chip has led to improvements in capacity, speed, and power consumption, largely due to our ability to purify semiconductor materials, leverage more sophisticated tools like chemical etching, and improve clean room technology. That all started with the integrated circuit chip.
Integrated circuit chips were invented around 1958, fueled by the discoveries of a few different people who solved different challenges nearly simultaneously. Jack Kilby of Texas Instruments created a hybrid integrated circuit measuring about 7/16” by 1/16” (11.1 mm by 1.6 mm). Robert Noyce (eventual co-founder of Intel) went on to create the first monolithic integrated circuit chip (so, all circuits held on the same chip) and it was around the same size. Here’s a blown-up version of it, held by Noyce:
Note those first chips only held about 60 transistors. Current chips can have billions of transistors etched onto the same microchip, and are even smaller. Here’s an example of what a integrated circuit looks like when it’s exposed:
And, that, folks, is one of the reasons you can now have a whole computer in your pocket in the guise of a smartphone. As you can imagine, something the size of a modern laptop or rack-mounted server can combine more of these elements more effectively. Hence, the rise of AI.
One More Acronym: What are FGPAs?
So far, I’ve described fixed, physical points on a chip, but chip performance is also affected by software. Software represents the logic and instructions for how all these things work together. So, when you create a chip, you have two options: you either know what software you’re going to run and create a customized chip that supports that, or you get a chip that acts like a blank slate and can be reprogrammed based on what you need.
The first method is called application-specific integrated circuits (ASIC). However, just like any proprietary build in manufacturing, you need to build them at scale for them to be profitable, and they’re slower to produce. Both CPUs and GPUs typically run on hard-etched chips like this.
Reprogrammable chips are known as field-programmable gate arrays (FPGA). They’re flexible and come with a variety of standard interfaces for developers. That means they’re incredibly valuable for AI applications, and particularly deep learning algorithms—as things rapidly advance, FPGAs can be continuously reprogrammed with multiple functions on the same chip, which lets developers test, iterate, and deliver them to market quickly. This flexibility is most notable in that you can also reprogram things like the input/output (IO) interface, so you can reduce latency and overcome bottlenecks. For that reason, folks will often compare the efficacy of the whole class of ASIC-based processors (CPUs, GPUs, NPUs, TPUs) to FPGAs, which, of course, has also led to hybrid solutions.
Summing It All Up: Chip Technology is Rad
Improvements in materials science and microchip construction laid the foundation for providing the processing capacity required by AI, and big players in the industry (Nvidia, Intel, Google, Microsoft, etc.) have leveraged those chips to create specialized processors.
Simultaneously, software has allowed many processing cores to be networked in order to control and distribute processing loads for increased speeds. All that has led us to the rise in specialized chips that enable the massive demands of AI.
Hopefully you have a better understanding of the different chipsets out there, how they work, and the difference between them. Still have questions? Let us know in the comments.
This post has been updated since it was originally published.
Your faithful Mac has served you well for years, but it’s time to upgrade. Whether you’re selling it, giving it to a friend, donating it, or recycling it, you first need to make sure all of your personal data is wiped clean.
In this guide, we’ll take you through the process step-by-step, from backing up your files to encrypting your data, so you can make sure your private information stays private.
Before you do anything else, back up
Once you wipe your Mac, you won’t be able to access the data from your drive. Before you get started, you’ll want to make sure any important data on your hard drive has been backed up. Apple has a built-in backup utility called Time Machine backup software.
While Time Machine is a good start, it doesn’t fulfill all of the requirements of a 3-2-1 backup strategy: When you set up Time Machine backups, you choose a backup disk (an external drive or network attached storage (NAS) device) that you can save your backups to. Under the 3-2-1 backup rule (three backups, on two media types, with one off-site), that means you’d still need an off-site copy of your data, preferably saved in the cloud. Ideally, you’d pair Time Machine with a product like Backblaze Computer Backup for maximum flexibility. Note that even though backups run nearly continuously with Backblaze Computer Backup, we recommend hitting the manual backup button before you wipe your Mac to ensure you’ve got the most recent information.
Mac operating systems (OSes) and processing chips: Figuring out what you have
The process for wiping your Mac depends on a couple things:
What OS version you’re rocking
What kind of processing chip you have
Fortunately, Apple has only made it easier to wipe your computer as the years and operating systems have rolled out. If you’re using macOS Monterey or later with an Apple-based processor chip, it’s very simple—you have the option to wipe your Mac from the System Settings.
What macOS do I have?
You can see your current OS in the About This Mac screen (from the Apple menu in the upper-left corner of your screen, choose About This Mac), and below is a list of all OS releases you can compare against. You can also check out the Apple Help article on the topic.
What kind of processing chip do I have in my Mac?
The second variable you need to know is what kind of processing chip you have in your Mac—an Apple-based chip (Apple M-series) or an Intel chip.
In November 2020, Apple launched its first Macs equipped with M1 chips, replacing the Intel-based processors of the past. The evolution of the M-series Apple chips has been notable largely for performance enhancements, but given that (at the time of publishing) this was four years ago, there’s a good chance that many users will have an Intel processor.
To see what kind of chip you have, follow the same instructions as above—go to your Apple menu and select About This Mac. If you have an M-series chip, you’ll see that listed as marked in the screenshot below.
If you have an Intel-based Mac, you will see Processor, followed by the name of an Intel processor.
How to wipe your Mac
Okay, so now that you know your operating system and processing chip, we can get to the actual how-to of how to wipe your Mac. The steps will be slightly different based on each of the above variables. Let’s dig in.
Wipe a Mac with an Apple chip and a recent macOS update
If you have macOS Monterey or later with an Apple chip, then you’re going to wipe your Mac using the Erase All Content and Settings function. (You might also see this called the Erase Assistant in Apple’s Help articles.) This will delete all your data, including iCloud and Apple logins, Apple wallet information, Bluetooth pairings, fingerprint sensor profiles, and Find My Mac settings, as well as resetting your Mac to factory settings. Here’s how you find it.
If you have macOS Ventura or Sonoma:
Select the Apple menu.
Choose System Settings.
Click General in the sidebar.
Click Transfer or Reset on the right.
If you have macOS Monterey:
Select the Apple Menu.
Choose System Preferences.
Once the System Preferences window is open, select the dropdown menu in your top navigation bar. Then, select Erase All Content and Settings.
Once you’ve reached this point, then the steps will be the same for each process. Here’s what to expect.
You’ll be prompted to log in with your administrator credentials.
Next, you will be reminded to back up via Time Machine. Remember that if you choose this option, you’ll want to back up to an external device—because, of course, you’re about to get rid of all the data stored on this computer.
Click Continue to allow all your settings, data, accounts, etc. to be removed.
If you’re asked to sign out of Apple ID, enter your Apple password and hit Continue.
Click Erase all Content & Settings to confirm.
Your Mac will automatically restart. If you have an accessory like a Bluetooth keyboard, you’ll be prompted to reconnect that device.
Select a WiFi network or attach a network cable.
After joining a network, your Mac activates. Click Restart.
After your device has restarted, a setup assistant will launch (just like when you first got your Mac).
It’ll be pretty clear if you don’t meet the conditions to erase your drive using this method because you won’t see Erase All Content and Settings on the System Settings we showed you above. So, here are instructions for the other methods.
How to wipe a Mac with an Apple chip using Disk Utility
Disk Utility is exactly what it sounds like: a Mac system application that helps you to manage your various storage volumes. You’d use it to manage storage if you have additional storage volumes, like a NAS or external hard drive; to set up a partition on your drive; to create a disk image (basically, a backup); or to simply give your disks a check up if they’re acting funky.
You can access Disk Utility at any time by selecting Finder > Go > Utilities, but you can also trigger Disk Utility on startup as outlined below.
Turn on your Mac and continue to press and hold the power button until the startup options window comes up. Click Options, then click Continue.
You may be prompted to log in with either your administrative password or your Apple ID.
When the Utilities window appears, select Disk Utility and hit Continue.
If you’d previously added other drives to your startup disk, click the delete volume button (–) to erase them.
Then, choose Macintosh HD in the sidebar.
Click the Erase button, then select a file system format and enter a name for it. For Macs with an M1 chip, your option for a file system format is only Apple File System (APFS).
Click Erase or, if it’s an option, Erase Volume Group. You may be asked for your Apple ID at this point.
You’ll be prompted to confirm your choice, then your computer will restart.
Just as in the other steps, when the computer restarts, it will attempt to activate by connecting to WiFi or asking you to attach a network cable.
After it activates, select Exit to Recovery Utilities.
Once it’s done, the Mac’s hard drive will be clean as a whistle and ready for its next adventure: a fresh installation of the macOS, being donated to a relative or a local charity, or just sent to an e-waste facility. Of course, you can still drill a hole in your disk or smash it with a sledgehammer if it makes you happy, but now you know how to wipe the data from your old computer with much less ruckus.
How to wipe a Mac with an Intel Processor using Disk Utility
Last but not least, let’s talk about how to wipe an Intel-based Mac.
Starting with your Mac turned off, press the power button, then immediately hold down the command (⌘) and R keys and wait until the Apple logo appears. This will launch macOS Recovery.
You may be prompted to log in with an administrator account password.
When the Recovery window appears, select Disk Utility.
In the sidebar, choose Macintosh HD.
Click the Erase button, then select a file system format and enter a name for it. Your options for a file system format include APFS, which is the file system used by macOS 10.13 or later, and macOS Extended, which is the file system used by macOS 10.12 or earlier.
Click Erase or Erase Volume Group. You may be prompted to provide your Apple ID.
If you previously used Disk Utility to add other storage volumes, you can erase them individually using the process above.
When you’ve deleted all your drives, quit Disk Utility to return to the utilities window. You may also choose to restart your computer at this point.
Do you still need to know what kind of drive you have?
Wiping your Mac used to depend on what kind of drive you had—a hard disk drive (HDD) or solid state drive (SSD). As we’ve outlined above, today, the process depends on your OS and the type of chip you have. But some of you may have very old Macs you want to get rid of. Here we’ll talk a bit about HDDs vs SSDs and the impact that has on how you erase your computer.
Around 2010, Apple started moving to only SSD storage in many of its devices. That said, some Mac desktop computers continued to offer the option of both SSD and HDD storage until 2020, a setup they called a Fusion Drive. The Fusion Drive is not to be confused with flash storage, a term that refers to the internal storage that holds your readily available and most accessed data at lower power settings.
Note that as of November 2021, Apple does not offer any Macs with a Fusion Drive. Basically, if you bought your device before 2010 or you have a desktop computer from 2021 or earlier, there’s a chance you may be using an HDD.
To determine what kind of drive your Mac uses, click on the Apple menu and select About This Mac.
Avoid the pitfall of selecting the Storage tab in the top menu. What you’ll find is that the default name of your drive is “Macintosh HD” which is confusing, given that they’re referring to the internal storage of the computer as a hard drive when (in most cases), your drive is an SSD. While you can find information about your drive on this screen, we prefer the method that provides maximum clarity.
So, on the Overview screen, click System Report. Bonus: You’ll also see what type of processor you have and your macOS version (which will be useful later).
Once there, select the Storage tab, then the volume name you want to identify. You should see a line called Medium Type, which will tell you what kind of drive you have.
Securely erasing drives: Questions and considerations
Some of you drive experts out there might remember that there is some nuance to security when it comes to erasing drives, and that there are differences in erasing HDDs versus SSDs. Without detouring into why and how that’s the case, just know that on Fusion Drives or Intel-based Macs, you may see additional security options you can enable when erasing HDDs.
There are four options in the “Security Options” slider. “Fastest” is quick but insecure—data could potentially be rebuilt using a file recovery app. Moving that slider to the right introduces progressively more secure erasing. Disk Utility’s most secure level erases the information used to access the files on your disk, then writes zeros across the disk surface seven times to help remove any trace of what was there. This setting conforms to the DoD 5220.22-M specification. Bear in mind that the more secure method you select, the longer it will take. The most secure methods can add hours to the process. For peace of mind, we suggest choosing the most secure option to erase your hard drive. You can always start the process in the evening and let it run overnight.
After the process is complete, restart your Mac and see if you can find any data. A quick inspection is not foolproof, but it can provide some peace of mind that the process finished without an interruption.
Securely erasing SSDs and why not to
If your Mac comes equipped with an SSD, Apple’s Disk Utility software won’t actually let you zero the drive. Sounds strange, right? Apple’s online Knowledge Base explains that secure erase options are not available in Disk Utility for SSDs.
Fortunately, you are not restricted to using the standard erasure option to protect yourself. Instead, you can use FileVault, a capability built into the operating system.
Encrypting your computer with FileVault
FileVault is an excellent option to protect all of the data on a Mac SSD with encryption. FileVault is whole-disk encryption for the Mac. With FileVault engaged, you need a password to access the information on your hard drive. Even without it, your data is encrypted and it would be very difficult for anybody else to access.
Before you use FileVault, there is a crucial downside. If you lose your password or the encryption key, your data may be gone for good!
When you first set up a new Mac, you’re given the option of turning FileVault on. If you don’t do it then, you can turn on FileVault at any time by clicking on your Mac’s System Preferences, clicking on Security & Privacy, and selecting the FileVault tab. Be warned, however, that the initial encryption process can take hours, as will decryption if you ever need to turn FileVault off.
With FileVault turned on, you can restart your Mac into its Recovery System following the directions above and erase your hard drive using Disk Utility, once you’ve unlocked it (by selecting the disk, clicking the File menu, and clicking Unlock). That deletes the FileVault key, which means any data on the drive is useless.
Nowadays, most Macs manage disk encryption through the T2 chip and its Secure Enclave, which is entirely separate from the main computer itself. This is why FileVault has no CPU overhead—it’s all handled by the T2 chip. Although FileVault doesn’t impact the performance of most modern Macs, we’d suggest only using it if your Mac has an SSD, not a conventional HDD.
Securely erasing free space on your SSD
If you don’t want to take Apple’s word for it, if you’re not using FileVault, or if you just want to, there is a way to securely erase free space on your SSD. It’s a little more involved, but it works. Before we get into the nitty-gritty, let me state for the record that this really isn’t necessary to do, which is why Apple’s made it so hard to do.
To delete all data from an SSD on an Apple computer, use Apple’s Terminal app. Terminal provides you with command line interface (CLI) access to the OS X operating system. Terminal lives in the Utilities folder, but you can access Terminal from the Mac’s Recovery System. Once your Mac has booted into the Recovery partition, click the Utilities menu and launch Terminal.
From a Terminal command line, type the following:
diskutil secureErase freespace VALUE /Volumes/DRIVE
That tells your Mac to securely erase the free space on your SSD. You’ll need to change value to a number between 0 and 4. Zero is a single-pass run of zeroes, 1 is a single-pass run of random numbers, 2 is a seven-pass erase, 3 is a 35-pass erase. Finally, level 4 is a three-pass erase with random fills plus a final zero fill. drive should be changed to the name of your hard drive. To run a seven-pass erase of your SSD drive in JohnB-MacBook, you would enter the following:
Note that while Mac’s Terminal typically uses forward slashes ( / ), if you have a space in the name of your hard drive, you’ll see a backslash ( \ ) to indicate that break in syntax. (So “Macintosh HD” becomes /Macintosh\ HD.) For example, to run a 35-pass erase on a hard drive called Macintosh HD, enter the following:
diskutil secureErase freespace 3 /Volumes/Macintosh\ HD
If you’re like the majority of computer users, you’ve never opened your Terminal application—and that’s probably a good thing. If you’re providing the proper instructions, a CLI lets you directly edit the guts of your computer. If you’re not providing the proper instructions, things will just error out, and likely you won’t know why.
In conclusion, in most cases, it’s simple to wipe your Mac hard drive
All this to say: Apple has made specific choices about designing products for folks who aren’t computer experts, and in most cases, you won’t need to break out the CLI knowledge to securely erase your hard drive. While Mac sometimes limits how customizable you can get on your device (i.e. it’s super hard to zero out an SSD), it’s usually for good reason—in this case, it’s to preserve the health of your drive in the long term. So, if you personally are planning to reuse the device you’re wiping, or if you’re not being targeted in a real-life James Bond movie, in most instances, it’s a less-than-ten step process to securely wipe your Mac and send it on to a new, shiny future.
FAQ
1. How do I wipe a Mac computer?
Wiping all data from your Mac depends on what macOS you’re using and what kind of processing chip you have. For Macs using macOS Monterey or later, you can use the Erase All Content and Settings function. This will delete all your data, including iCloud and Apple logins, Apple wallet information, Bluetooth pairings, fingerprint sensor profiles, and Find My Mac settings, as well as resetting your Mac to factory settings.
2. How do I wipe a Mac with an Intel processing chip?
To wipe a Mac with an Intel processing chip, you need to use Disk Utility, a Mac system application that helps you to manage your various storage volumes. You can access Disk Utility by selecting Finder > Go > Utilities. Choose Macintosh HD in the sidebar, click the Erase button, then select a file system format and enter a name for it. Your options for a file system format include Apple File System (APFS), which is the file system used by macOS 10.13 or later, and macOS Extended, which is the file system used by macOS 10.12 or earlier. Then click Erase or, if it’s an option, Erase Volume Group.
3. How do I encrypt data on my Mac?
FileVault is an excellent option to protect all of the data on a Mac SSD with encryption. FileVault is whole-disk encryption for the Mac. With FileVault engaged, you need a password to access the information on your hard drive. Even without it, your data is encrypted and it would be very difficult for anybody else to access.
This post has been updated since it was originally published. Unfortunately, ransomware continues to proliferate. We’ve updated the post to reflect the current state of ransomware and to help individuals and businesses protect their data.
Ransomware is one of the biggest cybersecurity threats that businesses and organizations face today. Cybercriminals use these malicious attacks to encrypt an organization’s data and systems, holding them hostage and demanding a ransom for the encryption key. In the best case scenario, you can quickly restore from backups, but it’s a harrowing experience even when you’re well prepared. That’s why it makes sense to assume it’s not a question of if, but when, and plan accordingly.
With attacks becoming increasingly sophisticated and widespread, it’s crucial for businesses to have a comprehensive plan for ransomware prevention and recovery. In this guide, we’ll cover best practices for recovering your data and systems in the event of an attack, as well as proactive measures to strengthen your defenses against ransomware.
This post is a part of our ongoing coverage of ransomware. Take a look at our other posts for more information on how businesses can defend themselves against a ransomware attack, and more.
The statistics paint a cautionary picture—ransomware attacks are only getting more common. According to a 2023 Ransomware Market Report, global ransomware costs are predicted to reach $265 billion annually by 2031, up from $20 billion in 2021.
After a brief downturn in both incidents and payments in 2022, ransomware surged back in 2023. Ransomware complaints rose to over 2,825, marking an 18% increase from the previous year. And payments exceeded $1 billion, a 96% increase from the previous year, representing the highest number ever observed. What’s more, 59% of organizations were hit by ransomware in the last year, according to Sophos’ State of Ransomware 2024 report.
Cyber criminals are continuously evolving their strategies, with the FBI noting new trends such as deploying multiple ransomware variants against the same victim and employing data destruction tactics to intensify pressure on victims to negotiate.
Ransomware by the numbers
According to the Coveware Q1 2024 Quarterly Report, the ransomware landscape saw some notable shifts in ransom demand tactics. The report states that in the first quarter of 2024, the average ransom payment continued a downward trajectory, decreasing by 32% from Q4 2023 to $381,980. However, the median ransom payment increased by 25% to $250,000.
Coveware analysts suggest this divergence is driven by fewer companies paying exorbitant ransoms, which has a compounding effect on lowering the average payment amount. Concurrently, many ransomware groups are deliberately setting more reasonable initial ransom demands, aiming to keep victims engaged in negotiations rather than deterring them outright with astronomical figures. This new approach of “reasonably” priced ransoms is an intentional tactic to increase the likelihood of victims paying.
The same Coveware report provides insights into the widespread impact of ransomware across various industries. Healthcare emerged as the most targeted sector at 18.7%, followed closely by professional services at 17.8%. The public sector, including government and educational institutions, was also heavily impacted at 11.2%.
Other notable industries affected were consumer services (10.3%), retail (5.6%), financial services, and food & staples retail (both 4.7%). The data illustrates that ransomware is a pervasive threat cutting across diverse sectors, from critical infrastructure like healthcare to consumer businesses and technology firms.
No industry seems immune, as even traditionally less digitized fields like materials (6.5%), capital goods (2.8%), and automobile manufacturing (3.7%) suffered attacks. This underscores the need for robust cybersecurity measures and ransomware readiness plans across diverse organizations, regardless of their primary domain of operations.
Ransomware also remains a significant threat across businesses of all sizes. However, small and medium sized businesses (SMBs) continue to bear the brunt of these attacks. A staggering 71.8% of impacted companies had between 11 and 1,000 employees, clearly demonstrating SMBs as a prime target for cybercriminals deploying ransomware.
While no organization is immune, the data highlights SMBs’ vulnerability, likely due to limited cybersecurity resources and staffing compared to larger enterprises. This highlights the critical need for SMBs to prioritize ransomware preparedness and implement robust security measures proportionate to the risks they face.
Simultaneously, the following chart indicates that ransomware groups are also setting their sights on major corporations, with 1.9% of impacted companies having over 100,000 employees. No sector can afford to be complacent about the pervasive ransomware threat landscape.
Ransomware as a service (Raas)
Ransomware as a service (RaaS) has emerged as a game changer in the world of cybercrime, revolutionizing the ransomware landscape and amplifying the scale and reach of malicious attacks. The RaaS business model allows even novice cybercriminals to access and deploy ransomware with relative ease, leading to a surge in the frequency and sophistication of ransomware attacks worldwide.
Traditionally, ransomware attacks required a high level of technical expertise and resources, limiting their prevalence to skilled cybercriminals or organized cybercrime groups. However, the advent of RaaS platforms has lowered the barrier to entry, making ransomware accessible to a broader range of individuals with nefarious intent. These platforms provide aspiring cybercriminals with ready-made ransomware toolkits, complete with user-friendly interfaces, step-by-step instructions, and even customer support. In essence, RaaS operates on a subscription or profit sharing model, allowing criminals to distribute ransomware and share the ransom payments with the RaaS operators.
The rise of RaaS has led to a proliferation of ransomware attacks, with cybercriminals exploiting the anonymity of the dark web to collaborate, share resources, and launch large scale campaigns. The RaaS model not only facilitates the distribution of ransomware, but it also provides criminals with analytics dashboards to track the performance of their campaigns, enabling them to optimize their strategies for maximum profit.
New strains and increased complexity
One of the most significant impacts of RaaS is the exponential growth in the number and variety of ransomware strains. RaaS platforms continuously evolve and introduce new ransomware variants, making it increasingly challenging for cybersecurity experts to develop effective countermeasures. The availability of these diverse strains allows cybercriminals to target different industries, geographical regions, and vulnerabilities, maximizing their chances of success.
The profitability of RaaS has attracted a new breed of cybercriminals, leading to an underground economy where specialized roles have emerged. Ransomware developers create and sell their malicious code on RaaS platforms, while affiliates or “distributors” spread the ransomware through various means, such as phishing emails, exploit kits, or compromised websites. This division of labor allows criminals to focus on their specific expertise, while RaaS operators facilitate the monetization process and collect a share of the ransoms.
Ransomware commoditization
The impact of RaaS extends beyond the immediate financial and operational consequences for targeted entities. The widespread availability of ransomware toolkits has also resulted in a phenomenon known as “ransomware commoditization,” where cybercriminals compete to offer their services at lower costs or even engage in price wars. This competition drives innovation and the continuous evolution of ransomware, making it a persistent and ever-evolving threat.
To combat the growing influence of RaaS, organizations and individuals require a multilayered approach to cybersecurity. Furthermore, organizations should prioritize data backups and develop comprehensive incident response plans to ensure quick recovery in the event of a ransomware attack. Regularly testing backup restoration processes is essential to maintain business continuity and minimize the impact of potential ransomware incidents.
RaaS has profoundly transformed the ransomware landscape, democratizing access to malicious tools and fueling the rise of cybercrime. The ease of use, scalability, and profitability of RaaS platforms have contributed to a surge in ransomware attacks across industries and geographic locations.
By staying vigilant and adopting robust cybersecurity measures, organizations can better protect themselves against the evolving threat posed by RaaS and ensure resilience in the face of potential ransomware incidents.
How does ransomware work?
A ransomware attack starts when a machine on your network becomes infected with malware. Cybercriminals have a variety of methods for infecting your machine, whether it’s an attachment in an email, a link sent via spam, or even through sophisticated social engineering campaigns. As users become more savvy to these attack vectors, cybercriminals’ strategies evolve. Once that malicious file has been loaded onto an endpoint, it spreads to the network, locking every file it can access behind strong encryption controlled by cybercriminals.
Types of ransomware, in addition to the traditional encryption model, include:
Non-encrypting ransomware or lock screens, which restrict access to files and data, but do not encrypt them.
Ransomware that encrypts a drive’s master boot record (MBR) or Microsoft’s NTFS, which prevents victims’ computers from being booted up in a live operating system (OS) environment.
Leakware or extortionware, which steals compromising or damaging data that the attackers then threaten to release if ransom is not paid. This type is on the rise—In 2023, 91% of ransomware attacks involved some sort of data exfiltration.
Mobile device ransomware which infects cell phones through drive-by downloads or fake apps.
What happens during a typical attack?
Threat actors have a lot of tools at their disposal to infiltrate systems, gather reconnaissance, and execute their mission. In cybersecurity parlance, these are called tactics, techniques, and procedures (TTPs). Without digging into too much detail, the typical lifecycle of a ransomware attack is as follows:
Initial compromise: Ransomware gains entry through various means such as exploiting known software vulnerabilities, using phishing emails or even physical media like thumb drives, brute-force attacks, and others. It then installs itself on a single endpoint or network device, granting the attacker remote access.
Secure key exchange: Once installed, the ransomware communicates with the perpetrator’s central command and control server, triggering the generation of cryptographic keys required to lock the system securely.
Encryption: With the cryptographic lock established, the ransomware initiates the encryption process, targeting files both locally and across the network, rendering them inaccessible without the decryption keys.
Extortion: Having gained secure and impenetrable access to your files, the ransomware displays an explanation of the next steps, including the ransom amount, instructions for payment, and the consequences of noncompliance.
Recovery options: At this stage, the victim can attempt to remove infected files and systems, restore from a clean backup, or some may consider paying the ransom.
It’s never advised to pay the ransom. According to Veeam’s 2024 Ransomware Trends Report, one in three organizations could not recover their data after paying the ransom. There’s no guarantee the decryption keys will work, and paying the ransom only further incentivizes cybercriminals to continue their attacks.
Who gets attacked?
Data has shown that ransomware attacks target firms of all sizes, and no business—from SMBs to large corporations—is immune. Attacks are on the rise in every sector and in every size of business. That said, small to medium-sized businesses are particularly vulnerable, as they may not have the resources needed to shore up their defenses and are often viewed as “easy targets” by cybercriminals.
Recent attacks where cybercriminals leaked sensitive photos of patients in a medical facility prove that no organization is out of bounds and no victim is off-limits. These attempts indicate that organizations which often have weaker controls and out-of-date or unsophisticated IT systems should take extra precautions to protect themselves and their data (especially their backup data!).
According to Veeam’s report, backup repositories are a prime target for bad actors. In fact, backup repositories are targeted in 96% of attacks, with bad actors successfully affecting the backup repositories in 76% of cases.
The U.S. consistently ranks highest in ransomware attacks, followed by the U.K. and Germany. Windows computers are the main targets, but ransomware strains exist for Macintosh and Linux, as well.
The unfortunate truth is that ransomware has become so widespread that most companies will certainly experience some degree of a ransomware or malware attack. The best they can do is be prepared and understand the best ways to minimize the impact of ransomware.
Backup repositories are targeted in 96% of attacks.
How to combat ransomware
So, you’ve been attacked by ransomware. Depending on your industry and legal requirements (which are ever-changing), you may be obligated to report the attack immediately. Otherwise, your footing should be one of damage control. What should you do next?
Isolate the infection. Swiftly isolate the infected endpoint from the rest of your network and any shared storage to halt the spread of the ransomware.
Identify the infection. With numerous ransomware strains in existence, it’s crucial to accurately identify the specific type you’re dealing with. Conduct scans of messages, files, and utilize identification tools to gain a clearer understanding of the infection.
Report the incident. While legal obligations may vary, it is advisable to report the attack to the relevant authorities. Their involvement can provide invaluable support and coordination for countermeasures.
Evaluate your options. Assess the available courses of action to address the infection. Consider the most suitable approach based on your specific circumstances.
Restore and rebuild. Utilize secure backups, trusted program sources, and reliable software to restore the infected systems or set up a new system from scratch.
1. Isolate the infection
Depending on the strain of ransomware you’ve been hit with, you may have little time to react. Fast-moving strains can spread from a single endpoint across networks, locking up your data as it goes, before you even have a chance to contain it.
The first step, even if you just suspect that one computer may be infected, is to isolate it from other endpoints and storage devices on your network. Disable Wi-Fi, disable Bluetooth, and unplug the machine from both any local area network (LAN) or storage device it might be connected to. This not only contains the spread but also keeps the ransomware from communicating with the attackers.
Know that you may be dealing with more than just one “patient zero.” The ransomware could have entered your system through multiple vectors, particularly if someone has observed your patterns before they attacked your company. It may already be laying dormant on another system. Until you can confirm, treat every connected and networked machine as a potential host to ransomware.
2. Identify the infection
Just as there are bad guys spreading ransomware, there are good guys helping you fight it. Sites like ID Ransomware and the No More Ransom! Project help identify which strain you’re dealing with. And knowing what type of ransomware you’ve been infected with will help you understand how it propagates, what types of files it typically targets, and what options, if any, you have for removal and disinfection. You’ll also get more information if you report the attack to the authorities (which you really should).
3. Report to the authorities
It’s understood that sometimes it may not be in your business’s best interest to report the incident. Maybe you don’t want the attack to be public knowledge. Maybe the potential downside of involving the authorities (lost productivity during investigation, etc.) outweighs the amount of the ransom. But reporting the attack is how you help everyone avoid becoming victimized and help combat the spread and efficacy of ransomware attacks in the future. With every attack reported, the authorities get a clearer picture of who is behind attacks, how they gain access to your system, and what can be done to stop them.
The good news is, you have options. The bad news is that the most obvious option, paying up, is a terrible idea.
Simply giving into cybercriminals’ demands may seem attractive to some, especially in those previously mentioned situations where paying the ransom is less expensive than the potential loss of productivity. Cybercriminals are counting on this.
However, paying the ransom only encourages attackers to strike other businesses or individuals like you. Paying the ransom not only fosters a criminal environment but also leads to civil penalties—and you might not even get your data back.
The other option is to try and remove it, or to start over.
5. Restore and rebuild—or start fresh
There are several sites and software packages that can potentially remove the ransomware from your system, including the No More Ransom! Project. Other options can be found, as well.
Whether you can successfully and completely remove an infection is up for debate. A working decryptor doesn’t exist for every known ransomware. The nature of the beast is that every time a good guy comes up with a decryptor, a bad guy writes new ransomware. To be safe, you’ll want to follow up by either restoring your system or starting over entirely.
Why starting over using your backups is the better idea
The surest way to confirm ransomware has been removed from a system is by doing a complete wipe of all storage devices and reinstalling everything from scratch. Formatting the hard disks in your system will ensure that no remnants of the ransomware remain.
To effectively combat the ransomware that has infiltrated your systems, it is crucial to determine the precise date of infection by examining file dates, messages, and any other pertinent information. Keep in mind that the ransomware may have been dormant within your system before becoming active and initiating significant alterations. By identifying and studying the specific characteristics of the ransomware that targeted your systems, you can gain valuable insights into its functionality, enabling you to devise the most effective strategy for restoring your systems to their optimal state.
A concerning 63% of organizations hastily restore directly back into compromised production environments without adequate scanning during recovery, risking re-introduction of the threat.
Select a backup or backups that were made prior to the date of the initial ransomware infection. If you’ve been following a sound backup strategy, you should have copies of all your documents, media, and important files right up to the time of the infection. With both local and off-site backups, you should be able to use backup copies that you know weren’t connected to your network after the time of attack, and hence, protected from infection. However, it is recommended to use a secure quarantine environment for testing before bringing production systems back online to ensure there is no dormant ransomware present in the data before restoring to production systems.
How Object Lock protects your backups
Object Lock functionality for backups allows you to store objects using a write once, read many (WORM) model, meaning that after it’s written, data cannot be modified. Using Object Lock, no one can encrypt, tamper with, or delete your protected data for a specified period of time, creating a solid line of defense against ransomware attacks.
Object Lock creates a virtual air gap for your data. The term “air gap” comes from the world of LTO tape. When backups are written to tape, the tapes are then physically removed from the network, creating a literal gap of air between backups and production systems. In the event of a ransomware attack, you could just pull the tapes from the previous day to restore systems. Object Lock does the same thing, but it all happens in the cloud. Instead of physically isolating data, Object Lock virtually isolates the data.
Object Lock is valuable in a few different use cases:
To replace an LTO tape system: Most folks looking to migrate from tape are concerned about maintaining the security of the air gap that tape provides. With Object Lock, you can create a backup that’s just as secure as air-gapped tape without the need for expensive physical infrastructure.
To protect and retain sensitive data: If you work in an industry that has strong compliance requirements—for instance, if you’re subject to HIPAA regulations or if you need to retain and protect data for legal reasons—Object Lock allows you to easily set appropriate retention periods to support regulatory compliance.
As part of a disaster recovery (DR) and business continuity plan: The last thing you want to worry about in the event you are attacked by ransomware is whether your backups are safe. Being able to restore systems from backups stored with Object Lock can help you minimize downtime and interruptions, comply with cyber insurance requirements, and achieve recovery time objectives (RTO) easier. By making critical data immutable, you can quickly and confidently restore uninfected data from your backups, deploy them, and return to business without interruption.
Ransomware attacks can be incredibly disruptive. By adopting the practice of creating immutable, air-gapped backups using Object Lock functionality, you can significantly increase your chances of achieving a successful recovery. This approach brings you one step closer to regaining control over your data and mitigating the impact of ransomware attacks.
So, why not just run a system restore?
While it might be tempting to rely solely on a system restore point to restore your system’s functionality, it is not the best solution for eliminating the underlying virus or ransomware responsible for the initial problem. Malicious software tends to hide within various components of a system, making it impossible for system restore to eradicate all instances.
Another critical concern is that ransomware has the capability to infect and encrypt local backups. If a computer is infected with ransomware, there is a high likelihood that your local backup solution will also suffer from data encryption, just like everything else on the system.
With a good backup solution that is isolated from your local computers, you can easily obtain the files you need to get your system working again. This will also give you the flexibility to determine which files to restore from a particular date and how to obtain the files you need to restore your system.
Initial compromise TTPs: Human attack vectors
Often, the weak link in your security protocol is the ever-elusive X factor of human error. Cybercriminals know this and exploit it through social engineering. In the context of information security, social engineering is the use of deception to manipulate individuals into divulging confidential or personal information that may be used for fraudulent purposes. In other words, the weakest point in your system is usually somewhere between the keyboard and the chair.
Common human attack vectors include:
1. Phishing
Phishing uses seemingly legitimate emails to trick people into clicking on a link or opening an attachment, unwittingly delivering the malicious payload. The email might be sent to one person or many within an organization, but sometimes the emails are targeted to help them seem more credible. This targeting takes a little more time on the attackers’ part, but the research into individual targets can make their email seem even more legitimate, not to mention the assistance of generative AI models like ChatGPT. They might disguise their email address to look like the message is coming from someone the sender knows, or they might tailor the subject line to look relevant to the victim’s job. This highly personalized method is called “spear phishing.”
2. SMSishing
As the name implies, SMSishing uses text messages to get recipients to navigate to a site or enter personal information on their device. Common approaches use authentication messages or messages that appear to be from a financial or other service provider. Even more insidiously, some SMSishing ransomware variants attempt to propagate themselves by sending themselves to all contacts in the device’s contact list.
3. Vishing
In a similar manner to email and SMS, vishing uses voicemail to deceive the victim, leaving a message with instructions to call a seemingly legitimate number which is actually spoofed. Upon calling the number, the victim is coerced into following a set of instructions which are ostensibly to fix some kind of problem. In reality, they are being tricked into installing ransomware on their own computer. Like so many other methods of phishing, vishing has become increasingly sophisticated with the spread of AI, with recent, successful deepfakes leveraging vishing to duplicate the voices of company higher-ups—to the tune of $25 million. And like spear phishing, it has become highly targeted.
4. Social media
Social media can be a powerful vehicle to convince a victim to open a downloaded image from a social media site or take some other compromising action. The carrier might be music, video, or other active content that, once opened, infects the user’s system.
5. Instant Messaging
Between them, IM services like WhatsApp, Facebook Messenger, Telegram, and Snapchat have more than four billion users, making them an attractive channel for ransomware attacks. These messages can seem to come from trusted contacts and contain links or attachments that infect your machine and sometimes propagate across your contact list, furthering the spread.
Ransomware is more about manipulating vulnerabilities in human psychology than the adversary’s technological sophistication.”
—James Scott, Institute for Critical Infrastructure Technology
Initial compromise TTPs: Machine attack vectors
The other type of attack vector is machine to machine. Humans are involved to some extent, as they might facilitate the attack by visiting a website or using a computer, but the attack process is automated and doesn’t require any explicit human cooperation to invade your computer or network.
1. Drive-by
The drive-by vector is particularly malicious, since all a victim needs to do is visit a website carrying malware within the code of an image or active content. As the name implies, all you need to do is cruise by and you’re a victim.
2. Known system vulnerabilities
Cybercriminals learn the vulnerabilities of specific systems and exploit those vulnerabilities to break in and install ransomware on the machine. This happens most often to systems that are not patched with the latest security releases.
3. Malvertising
Malvertising is like drive-by, but uses ads to deliver malware. These ads might be placed on search engines or popular social media sites in order to reach a large audience. A common host for malvertising is adults-only sites.
4. Network propagation
Once a piece of ransomware is on your system, it can scan for file shares and accessible computers and spread itself across the network or shared system. Companies without adequate security might have their company file server and other network shares infected as well. From there, the malware will propagate as far as it can until it runs out of accessible systems or meets security barriers.
5. Propagation through shared services
Online services such as file sharing or syncing services can be used to propagate ransomware. If the ransomware ends up in a shared folder on a home machine, the infection can be transferred to an office or to other connected machines. If the service is set to automatically sync when files are added or changed, as many file sharing services are, then a malicious virus can be widely propagated in just milliseconds.
It’s important to be careful and consider the settings you use for systems that automatically sync, and to be cautious about sharing files with others unless you know exactly where they came from.
Prevention best practices
Security experts suggest several precautionary measures for preventing a ransomware attack.
Use antivirus and antimalware software or other security policies to block known payloads from launching.
Make frequent, comprehensive backups of all important files and isolate them from local and open networks.
Immutable backup options such as Object Lock offer users a way to maintain truly air-gapped backups. The data is fixed, unchangeable, and cannot be deleted within the time frame set by the end user.
Keep offline data backups stored in locations that are air gapped or inaccessible from any potentially infected computer, such as on disconnected external storage drives or in the cloud, which prevents the ransomware from accessing them.
Keep your security up-to-date through trusted vendors of your OS and applications. Remember to patch early and patch often to close known vulnerabilities in operating systems, browsers, and web plugins.
Consider deploying security software to protect endpoints, email servers, and network systems from infection.
Segment your networks to keep critical computers isolated and to prevent the spread of ransomware in case of an attack. Turn off unneeded network shares.
Operate on the principle of least privilege. Turn off admin rights for users who don’t require them. Give users the lowest system permissions they need to do their work.
Restrict write permissions on file servers as much as possible.
Educate yourself and your employees in best practices to keep ransomware out of your systems. Update everyone on the latest email phishing scams and human engineering aimed at turning victims into abettors.
It’s clear that the best way to respond to a ransomware attack is to avoid having one in the first place. Other than that, making sure your valuable data is backed up and unreachable to a ransomware infection will ensure that your downtime and data loss will be minimal if you ever fall prey to an attack.
Have you endured a ransomware attack or have a strategy to keep you from becoming a victim? Please let us know in the comments.
Ransomware FAQS
What is a ransomware attack?
A ransomware attack is a type of cyberattack where cybercriminals or groups gain access to a computer system or network and encrypt valuable files or data, making them inaccessible to the owner. The attackers then demand a ransom, usually in the form of cryptocurrency, in exchange for providing the decryption key to unlock the files. Attackers may also extort victims by exfiltrating and threatening to leak sensitive data. Ransomware attacks can cause significant financial losses, operational disruptions, and potential data breaches if the ransom is not paid or effective countermeasures are not implemented.
How do I prevent ransomware attacks?
Preventing ransomware requires a proactive approach to cybersecurity and cyber resilience. Implement robust security measures, including regularly updating software and operating systems, utilizing strong and unique passwords, and deploying reputable antivirus and antimalware software. Train employees about how to identify phishing and social engineering tactics. Regularly back up critical data to cloud storage, implement tools like Object Lock to create immutability, and test your restoration processes. Lastly, stay informed about the latest threats and security best practices to fortify your defenses against ransomware.
How does ransomware work?
Ransomware gains entry through various means such as phishing emails, physical media like thumb drives, or alternative methods. It then installs itself on one or more endpoints or network devices, granting the attacker access. Once installed, the ransomware communicates with the perpetrator’s central command and control server, triggering the generation of cryptographic keys required to lock the system securely. With the cryptographic lock established, the ransomware initiates the encryption process, targeting files both locally and across the network, and renders them inaccessible without the decryption keys.
How does ransomware spread?
Common ransomware attack vectors include malicious email attachments or links, where users unknowingly download or execute the ransomware payload. It can also spread through exploit kits that target vulnerabilities in software or operating systems. Ransomware may propagate through compromised websites, drive-by downloads, or via malicious ads. Additionally, attackers can utilize brute force attacks to gain unauthorized access to systems and deploy ransomware.
How do I recover from a ransomware attack?
First, contain the infection. Isolate the infected endpoint from the rest of your network and any shared storage. Next, identify the infection. With numerous ransomware strains in existence, it’s crucial to accurately identify the specific type you’re dealing with. Conduct scans of messages, files, and utilize identification tools to gain a clearer understanding of the infection. Report the incident. While legal obligations may vary, it is advisable to report the attack to the relevant authorities. Their involvement can provide invaluable support and coordination for countermeasures. Then, assess the available courses of action to address the infection. If you have a solid backup strategy in place, you can utilize secure backups to restore and rebuild your environment.
Have you ever had that nagging feeling that you are forgetting something important? It’s like when you were back in school and sat down to take a test, only to realize you studied the wrong material. Worrying about your business data can feel like that. Are you fully protected? Are you doing all you can to ensure your data is backed up, safe, and easily restorable?
If you aren’t backing up your Microsoft 365 data, you could be leaving yourself unprepared and exposed. It’s a common misconception that data stored in software as a service (SaaS) products like Microsoft 365 is already backed up because it’s in a cloud application. But, anyone who’s tried to restore an entire company’s Microsoft 365 instance can tell you that’s not the case.
In this post, you’ll get a better understanding of how your Microsoft 365 data is stored and how to back it up so you can reliably and quickly restore it should you ever need to.
What Is Microsoft 365?
More than one million companies worldwide use Microsoft 365 (formerly Office 365). Microsoft 365 is a cloud-based productivity platform that includes a suite of popular applications like Outlook, Teams, Word, Excel, PowerPoint, Access, OneDrive, Publisher, SharePoint, and others.
Chances are that if you’re using Microsoft 365, you use it daily for all your business operations and rely heavily on the information stored within the cloud. But have you ever checked out the backup policies in Microsoft 365?
If you are not backing up your Microsoft 365 data, you have a gap in your backup strategy which may put your business at risk. If you suffer a malware or ransomware attack, natural disaster, or even accidental deletion by an employee, you could lose that data. In addition, it may cost you a lot of time and money trying to restore from Microsoft after a data emergency.
Why You Need to Back Up M365
You might assume that, because it’s in the cloud, your SaaS data is backed up automatically for you. In reality, SaaS companies and products like Microsoft 365 operate on a shared responsibility model, meaning they back up the data and infrastructure to maintain uptime, not to help you in the event you need to restore. Practically speaking, that means that they may not back up your data as often as you would like or archive it for as long as you need. Microsoft does not concern itself with fully protecting your files. Most importantly, they may not offer a timely recovery option if you lose the data, which is critical to getting your business back online in the event of an outage.
The bottom line is that Microsoft’s top priority is to keep its own services running. They replicate data and have redundancy safeguards in place to ensure you can access your data through the platform reliably, but they do not assume responsibility for their users’ data.
All this to say, you are ultimately responsible for backing up your data and files in Microsoft 365.
M365 Native Backup Tools
But wait—what about Microsoft 365’s native backup tools? If you are relying on native backup support for your crucial business data, let’s talk about why that may not be the best way to make sure your data is protected.
Retention Period and Storage Costs
First, there are default settings within Microsoft 365 that dictate how long items are retained in the Recycle Bin and Deleted Items folders. You can tweak those settings for a longer retention period, but there is also a storage limit, so you might run out of space quickly. To keep your data longer, you must upgrade your license type and purchase additional storage, which could quickly become costly. Additionally, if an employee accidentally or purposefully deletes items from the trash bin, the item may be gone forever.
Replication Is Not a Backup
Microsoft replicates data as part of its responsibility, but this doesn’t help you meet the requirements of a solid 3-2-1 strategy, where there are three copies of your data, one of which is off-site. So Microsoft doesn’t fully protect you and doesn’t support compliance standards that call for immutability. When Microsoft replicates data, they’re only making a second copy, and that copy is designed to be in sync with your production data. This means that an item gets corrupted and then replicated, the archive version is also corrupted, and you could lose crucial data. You can’t bank on M365’s replication to protect you.
Sync Is Not a Backup
Similarly, syncing is not backup protection and could end up hurting you. Syncing is designed to have a single copy of a file always up-to-date with changes you or other users have made on different devices. For example, if you use OneDrive as your cloud backup service, the bad news is that OneDrive will sync corrupted files overwriting your healthy ones. Essentially, if a file is deleted or infected, it will be infected or deleted on all synchronized devices. In contrast, a true backup allows you to restore from a specific point in time and provides access to previous versions of data, which can be useful in case of a ransomware attack or deletion.
Back Up Frequency and Control
Lastly, one of the biggest drawbacks of relying on Microsoft’s built-in backup tools is that you lack the ability to dial in your backup system the way you may want or need. There are several rules to follow in order to be able to recover or restore files in Microsoft 365. For instance, it’s strongly recommended that you save your documents in the cloud, both for syncing purposes and to enable things like Version History. But, if you delete an online-only file, it doesn’t go to your Recycle Bin, which means there’s no way to recover it.
And, there are limits to the maximum numbers of versions saved when using Version History, the period of time a file is recoverable for, and so on. Some of the recovery periods even change depending on file type. For example, you can’t restore email after 30 days, but if you have an enterprise-level account, other file types are stored in your Recycle Bin or trash for up to 93 days.
Backups may not be created as often as you like, and the recovery process isn’t quick or easy. For example, Microsoft backs up your data every 12 hours and retains it for 14 days. If you need to restore files, you must contact Microsoft Support, and they will perform a “full restore,” overwriting everything, not just the specific information you need. The recovery process probably won’t meet your recovery time objective (RTO) requirements.
Compliance and Cyber Insurance
Many people want more control over their backups than what Microsoft offers, especially for mission-critical business data. In addition to having clarity and control over the backup and recovery process, data storage and backups are often an essential element in supporting compliance needs, particularly if your business stores personal identifiable information (PII). Different industries and regions will have different standards that need to be enforced, so it’s always a good idea to have your legal or compliance team involved in the conversation.
Similarly, with the increasing frequency of ransomware attacks, many businesses are adding cyber insurance. Cyber insurance provides protection for a variety of things, including legal fees, expenditure related to breaches, court-ordered judgments, and forensic post-break review expenses. As a result, they often have stipulations about how and when you’re backing up to mitigate the fallout of business downtime.
Backing Up M365 With a Third Party Tool to the Cloud
Instead of the native Microsoft 365 backup tool, you could use one of the many popular backup applications that provide Microsoft 365 backup support. Options include:
Note that some of these applications include Microsoft 365 protection with their standard license, but it’s an optional add-on module with others. Be sure to check licensing and pricing before choosing an option.
One thing to keep in mind with these tools: if you store on-premises, the backup data they generate can be vulnerable to local disasters like fire or earthquakes and to cyberattacks. For example, if you keep backups on network attached storage (NAS) that doesn’t tier to the cloud, then your data would not be fully protected
Backing your data up to the cloud puts a copy off-site and geographically distant from your production data, so it’s better protected from things like natural disasters. When you’re choosing a cloud storage provider, make sure you check out where they store their data—if their data center is just down the road, then you’ll want to pick a different region.
Backblaze B2 + Microsoft 365
Backblaze B2 Cloud Storage is reliable, affordable, and secure backup cloud storage, and it integrates seamlessly with the third party applications listed above for backing up Microsoft 365. Some of the benefits of using Backblaze B2 include:
Retain your files as long as you want and back up as often as you’d like: Backblaze B2 is one-fifth of the cost of other cloud providers.
Restore data immediately: Backblaze B2 is always-hot so you never have to wait for cold storage delays.
Start backing up your Microsoft 365 data to Backblaze B2 today.
Protect Your M365 Data for Peace of Mind
Whether you are a business professional or an IT director, your goal is to protect your company data. Backing up your Microsoft 365 data to the cloud satisfies your RTO goals and better protects you against various threats.
Relying on Microsoft 365 native tools is inefficient and slow, which means you could blow your RTO targets. Backing up to the cloud allows you to meet retention requirements, ensuring that you retain the data you need for as long as required without destroying your operational budget.
Your business-critical data is too important to trust to a native backup tool that doesn’t meet your needs. In the event of a catastrophic situation, you need complete control and quick access to all your files from a specific point in time. Backing your Microsoft 365 data up to the cloud gives you more control, more freedom, and better protection.
Think for a second about that Android device in your hand. Maybe it’s a smartphone, maybe it’s a tablet. Whether it’s a Samsung, Google, or Motorola, it still has Android in its DNA. But more important than its DNA is the data stored in its memory.
You probably don’t think about how much irreplaceable data is in there—treasured photos, important documentation, passwords, bank information, the list goes on. But you might want to give it a few minutes of your time because, as smart as your phone is, it’s also remarkably fragile. A trip down the stairs or a dip in the toilet and your phone is toast, taking with it all of that important data. Opening one wrong email or clicking one wrong link could be all it takes for ransomware to infiltrate your data.
In cases like these, the best solution is an ounce of prevention: Getting all those important files backed up before disaster strikes.
Before we get your Droid all backed up and ready to roll, it’s important to understand why you should back up, why syncing isn’t enough, how different phones offer different means of backup, and why a 3-2-1 backup strategy should be your ultimate goal.
And since we’re talking Androids, we’ll obviously be spending a little time in a galaxy far, far away.
“Important to Back Up Your Data, It Is.” – Master Yoda, Probably
In order to understand the importance of backing up your Android, it might help to picture perhaps two of the most famous droids in cinematic history, and in fact the characters who inspired your phone’s name: R2-D2 and C-3PO.
(Seriously, Lucasfilm registered the trademark on the word “droid” in 1977 and has licensed it to both Motorola and Verizon. If you’re reading this, Disney, please don’t sue.)
If you recall the movie “The Force Awakens,” you’ll remember the sub-plot about the search for Luke Skywalker, who had gone into hiding. As the film opens, plucky little droid BB-8 obtained part of the map that could locate him. However, the rest of the map was locked away in R2-D2’s memory units, rendering BB-8’s map useless. Since R2-D2 was mysteriously shut down for purposes of advancing the movie’s plot, that data was unobtainable and thus required a whole film’s worth of daring adventure to restore.
Protection against data loss: Maybe your phone gets dropped into a pond or maybe it gets blasted by TIE fighters. Either way, without a proper backup that data is deader than Greedo.
Easy Upgrading: Jedi Master Qui-Gonn Jinn once said there’s always a bigger fish. Likewise, there’s always a shinier, newer Android device. When you upgrade, you can pull all your old data from your backup and get started with ease.
Protecting against ransomware, malware, and viruses: Even your phone is susceptible to attacks from cybercriminals who can lock up your data and demand payment to restore it. Backing it up is like sending your vital data blasting out through an escape pod just as the Empire descends for retrieval later.
I Have a Syncing Feeling About This
Fortunately, Princess Leia and company seem to have learned their lesson about proper backups by the time of “Rise of Skywalker,” since they had a backup ready for C-3PO. After wiping his hard drive so that the protocol droid could bypass his programming and read the Sith language found on an ancient knife (yes, the plot was that ridiculous), 3PO was able to restore his memories thanks to a backup he’d entrusted to R2.
Had they chosen to merely sync C-3PO’s internal data, he would have been stuck remembering nothing of the Star Wars saga except for “Rise of Skywalker,” which would be a tragic fate for anyone.
With syncing, data is maintained in one form across devices or platforms. This has its usefulness, especially when you can edit something on your phone or tablet and see those changes on your laptop, for example, but also has drawbacks that make it a poor substitute for backing up. Among them:
Limited coverage of what gets synced: Syncing will often focus on specific verticals within data, such as photos, contacts, or calendars. For example, when you make changes to a contact in your phone or device, Google will automatically update that contact in the cloud. But it won’t necessarily automatically update your call or text message history.
Overwriting or deleting data: If C-3PO had been set to sync his data with R2-D2, once it was deleted in his shiny golden head it would be deleted across all backups, and all of the data would have been lost before you could say “Utini.” If you delete your data from your phone, it gets deleted from whatever service you’re using to sync devices.
Vulnerability to ransomware: If you click a malicious link and your device gets zapped with ransomware, your sync service will automatically synchronize the corrupted files.
These Aren’t the Droids You’re Looking For
It’s all well and good to hear about backing up fictional droids, but what about the actual Android device in your hand? Thankfully, it’s somehow even simpler in our galaxy than it is in one where people have actual spaceships.
Both Google and Samsung have backup programs for their respective devices, and we’ll explain a third option where you manage the backups.
Google One
Native to Google’s Pixel devices, but also found on nearly every Android device since it was introduced in 2021, Google One offers a backup service analogous to iCloud, with 15GB of free storage tied to your Google account.
Sorry, potential stalkers. I remembered to blur my email address.
Pros: Works automatically. Backs up apps, phone history, text messages, photos, contacts, and assorted calendar information associated with your account. It can also load data automatically onto a new device when you sign in with your Google account.
Cons: You have to pick and choose what gets backed up. Yes, this is a con. This level of control might seem nice, but again, we’d recommend you just back up everything. Honestly, the more granular you get with what gets backed up, the more likely you are to forget to back up something you might need. It also operates more like a sync than a backup, so accidental erasure is still a risk. To truly back up your data and keep it safe, you’ll need to keep a third copy of the data somewhere (we’ll explain that later). Also, if you get close to maxing out your storage, ready yourself for endless reminders to buy more storage across all of your devices.
Samsung Smart Switch
As the heavy hitter in the Android space, Samsung wasn’t about to let its Galaxy devices go without a built-in backup solution. Samsung’s Smart Switch comes pre-loaded on every Galaxy device. While it’s designed for moving data from one Galaxy to another, it can also create a backup to your Mac or PC using the Smart Switch app.
Yeah, I’m still using an S21. Don’t @ me.
Backing Up Through Your Mac or PC
Of course, one of the great advantages of the Android operating system is its ability to play nice with pretty much every other operating system, unlike its Apple counterpart. Simply plug your charging cable into an available USB slot and your phone will essentially act like an external hard drive. On a Windows machine, this will show up like a separate hard drive nested under your PC in file explorer. On a Mac, you’ll need to take the extra step of downloading Android File Transfer.
Pros: Functions essentially like an external drive, meaning you can track down individual files or whole folders for targeted backup.
Cons: Android’s file structure can often make individual files difficult to track down. Transfer times can often drag on to the point of absurdity.
How to Back Up Your Life
The guides in this series help you protect your content across many different platforms. We’re working on developing this list—please comment below if you’d like to see another platform covered.
“Come On Buddy, We’re Not Out of This Yet.” – Han Solo, Shortly After Backing Up His Phone, Probably
Now that you have your data safely backed up and secured against any accidental destruction, loss, or damage to your Android, you might think you’re safe. But the cornerstone of any good backup strategy rests on not one, not two, but three pillars.
If you really need to be told why this is important, we’ve covered it here. But suffice to say, a 3-2-1 strategy relies on a trio of separate, redundant backups. One copy of your data stays on your Android device. Another copy of your data is stored on a separate on-premises device, such as your PC or an external hard drive (or, if available, a convenient R2-model astromech). Finally, a third copy stays off-premises—preferably in the cloud—to avoid the possibility of theft, fire, or total planetary destruction via Death Star.
If you’re a Backblaze Computer Backup user, that last step is taken care of. Backblaze backs up your entire computer, including any Android backups you saved to your Mac or PC.
By maintaining three redundant copies of important data—two on local devices and a third in a separate location—you are comprehensively protected against data loss. You may not be carrying around plans for the Empire’s new battle station, but the precious memories locked away on your Android device are just as important as protecting them.
May the force be with you (and again, Disney, please don’t sue).
This post was originally published in 2018 and updated in 2021. We’re sharing an update to this post to provide the latest information on VMs and containers.
Both virtual machines (VMs) and containers help you optimize computer hardware and software resources via virtualization.
Containers have been around for a while, but their broad adoption over the past few years has fundamentally changed IT practices. On the other hand, VMs have enjoyed enduring popularity, maintaining their presence across data centers of various scales.
As you think about how to run services and build applications in the cloud, these virtualization techniques can help you do so faster and more efficiently. Today, we’re digging into how they work, how they compare to each other, and how to use them to drive your organization’s digital transformation.
First, the Basics: Some Definitions
What Is Virtualization?
Virtualization is the process of creating a virtual version or representation of computing resources like servers, storage devices, operating systems (OS), or networks that are abstracted from the physical computing hardware. This abstraction enables greater flexibility, scalability, and agility in managing and deploying computing resources. You can create multiple virtual computers from the hardware and software components of a single machine. You can think of it as essentially a computer-generated computer.
What Is a Hypervisor?
The software that enables the creation and management of virtual computing environments is called a hypervisor. It’s a lightweight software or firmware layer that sits between the physical hardware and the virtualized environments and allows multiple operating systems to run concurrently on a single physical machine. The hypervisor abstracts and partitions the underlying hardware resources, such as central processing units (CPUs), memory, storage, and networking, and allocates them to the virtual environments. You can think of the hypervisor as the middleman that pulls resources from the raw materials of your infrastructure and directs them to the various computing instances.
There are two types of hypervisors:
Type 1, bare-metal hypervisors, run directly on the hardware.
Type 2 hypervisors operate within a host operating system.
Hypervisors are fundamental to virtualization technology, enabling efficient utilization and management of computing resources.
VMs and Containers
What Are VMs?
The computer-generated computers that virtualization makes possible are known as virtual machines (VMs)—separate virtual computers running on one set of hardware or a pool of hardware. Each virtual machine acts as an isolated and self-contained environment, complete with its own virtual hardware components, including CPU, memory, storage, and network interfaces. The hypervisor allocates and manages resources, ensuring each VM has its fair share and preventing interference between them.
Each VM requires its own OS. Thus each VM can host a different OS, enabling diverse software environments and applications to exist without conflict on the same machine. VMs provide a level of isolation, ensuring that failures or issues within one VM do not impact others on the same hardware. They also enable efficient testing and development environments, as developers can create VM snapshots to capture specific system states for experimentation or rollbacks. VMs also offer the ability to easily migrate or clone instances, making it convenient to scale resources or create backups.
Since the advent of affordable virtualization technology and cloud computing services, IT departments large and small have embraced VMs as a way to lower costs and increase efficiencies.
VMs, however, can take up a lot of system resources. Each VM runs not just a full copy of an OS, but a virtual copy of all the hardware that the operating system needs to run. It’s why VMs are sometimes associated with the term “monolithic”—they’re single, all-in-one units commonly used to run applications built as single, large files. (The nickname, “monolithic,” will make a bit more sense after you learn more about containers below.) This quickly adds up to a lot of RAM and CPU cycles. They’re still economical compared to running separate actual computers, but for some use cases, particularly applications, it can be overkill, which led to the development of containers.
Benefits of VMs
All OS resources available to apps.
Well-established functionality.
Robust management tools.
Well-known security tools and controls.
The ability to run different OS on one physical machine.
Cost savings compared to running separate, physical machines.
With containers, instead of virtualizing an entire computer like a VM, just the OS is virtualized.
Containers sit on top of a physical server and its host OS—typically Linux or Windows. Each container shares the host OS kernel and, usually, the binaries and libraries, too, resulting in more efficient resource utilization. (See below for definitions if you’re not familiar with these terms.) Shared components are read-only.
Why are they more efficient? Sharing OS resources, such as libraries, significantly reduces the need to reproduce the operating system code—a server can run multiple workloads with a single operating system installation. That makes containers lightweight and portable—they are only megabytes in size and take just seconds to start. What this means in practice is you can put two to three times as many applications on a single server with containers than you can with a VM. Compared to containers, VMs take minutes to run and are an order of magnitude larger than an equivalent container, measured in gigabytes versus megabytes.
Container technology has existed for a long time, but the launch of Docker in 2013 made containers essentially industry standard for application and software development. Technologies like Docker or Kubernetes to create isolated environments for applications. And containers solve the problem of environment inconsistency—the old “works on my machine” problem often encountered in software development and deployment.
Developers generally write code locally, say on their laptop, then deploy that code on a server. Any differences between those environments—software versions, permissions, database access, etc.—leads to bugs. With containers, developers can create a portable, packaged unit that contains all of the dependencies needed for that unit to run in any environment whether it’s local, development, testing, or production. This portability is one of containers’ key advantages.
Containers also offer scalability, as multiple instances of a containerized application can be deployed and managed in parallel, allowing for efficient resource allocation and responsiveness to changing demand.
Microservices architectures for application development evolved out of this container boom. With containers, applications could be broken down into their smallest component parts or “services” that serve a single purpose, and those services could be developed and deployed independently of each other instead of in one monolithic unit.
For example, let’s say you have an app that allows customers to buy anything in the world. You might have a search bar, a shopping cart, a buy button, etc. Each of those “services” can exist in their own container, so that if, say, the search bar fails due to high load, it doesn’t bring the whole thing down. And that’s how you get your Prime Day deals today.
More Definitions: Binaries, Libraries, and Kernels
Binaries: In general, binaries are non-text files made up of ones and zeros that tell a processor how to execute a program.
Libraries: Libraries are sets of prewritten code that a program can use to do either common or specialized things. They allow developers to avoid rewriting the same code over and over.
Kernels: Kernels are the ringleaders of the OS. They’re the core programming at the center that controls all other parts of the operating system.
Container Tools
Linux Containers (LXC): Commonly known as LXC, these are the original Linux container technology. LXC is a Linux operating system-level virtualization method for running multiple isolated Linux systems on a single host.
Docker: Originally conceived as an initiative to develop LXC containers for individual applications, Docker revolutionized the container landscape by introducing significant enhancements to improve their portability and versatility. Gradually evolving into an independent container runtime environment, Docker emerged as a prominent Linux utility, enabling the seamless creation, transportation, and execution of containers with remarkable efficiency.
Kubernetes: Kubernetes, though not a container software in its essence, serves as a vital container orchestrator. In the realm of cloud-native architecture and microservices, where applications deploy numerous containers ranging from hundreds to thousands or even billions, Kubernetes plays a crucial role in automating the comprehensive management of these containers. While Kubernetes relies on complementary tools like Docker to function seamlessly, it’s such a big name in the container space it wouldn’t be a container post without mentioning it.
Benefits of Containers
Reduced IT management resources.
Faster spin ups.
Smaller size means one physical machine can host many containers.
Reduced and simplified security updates.
Less code to transfer, migrate, and upload workloads.
What’s the Diff: VMs vs. Containers
The virtual machine versus container debate gets at the heart of the debate between traditional IT architecture and contemporary DevOps practices.
VMs have been, and continue to be, tremendously popular and useful, but sadly for them, they now carry the term “monolithic” with them wherever they go like a 25-ton Stonehenge around the neck. Containers, meanwhile, pushed the old gods aside, bedecked in the glittering mantle of “microservices.” Cute.
To offer another quirky tech metaphor, VMs are to containers what glamping is to ultralight backpacking. Both equip you with everything you need to survive in the wilds of virtualization. Both are portable, but containers will get you farther, faster, if that’s your goal. And while VMs bring everything and the kitchen sink, containers leave the toothbrush at home to cut weight. To make a more direct comparison, we’ve consolidated the differences into a handy table:
VMs
Containers
Heavyweight.
Lightweight.
Limited performance.
Native performance.
Each VM runs in its own OS.
All containers share the host OS.
Hardware-level virtualization.
OS virtualization.
Startup time in minutes.
Startup time in milliseconds.
Allocates required memory.
Requires less memory space.
Fully isolated and hence more secure.
Process-level isolation, possibly less secure.
Uses for VMs vs. Uses for Containers
Both containers and VMs have benefits and drawbacks, and the ultimate decision will depend on your specific needs.
When it comes to selecting the appropriate technology for your workloads, virtual machines (VMs) excel in situations where applications demand complete access to the operating system’s resources and functionality. When you need to run multiple applications on servers, or have a wide variety of operating systems to manage, VMs are your best choice. If you have an existing monolithic application that you don’t plan to or need to refactor into microservices, VMs will continue to serve your use case well.
Containers are a better choice when your biggest priority is maximizing the number of applications or services running on a minimal number of servers and when you need maximum portability. If you are developing a new app and you want to use a microservices architecture for scalability and portability, containers are the way to go. Containers shine when it comes to cloud-native application development based on a microservices architecture.
You can also run containers on a virtual machine, making the question less of an either/or and more of an exercise in understanding which technology makes the most sense for your workloads.
In a nutshell:
VMs help companies make the most of their infrastructure resources by expanding the number of machines you can squeeze out of a finite amount of hardware and software.
Containers help companies make the most of the development resources by enabling microservices and DevOps practices.
Are You Using VMs, Containers, or Both?
If you are using VMs or containers, we’d love to hear from you about what you’re using and how you’re using them. Drop a note in the comments.
A little over a year ago, we announced general availability of Backblaze Cloud Replication, the ability to automatically copy data across buckets, accounts, or regions. There are several ways to use this service, but today we’re focusing on how to use Cloud Replication to replicate data between environments like testing, staging, and production when developing applications.
First we’ll talk about why you might want to replicate environments and how to go about it. Then, we’ll get into the details: there are some nuances that might not be obvious when you set out to use Cloud Replication in this way, and we’ll talk about those so that you can replicate successfully.
Other Ways to Use Cloud Replication
In addition to replicating between environments, there are two main reasons you might want to use Cloud Replication:
Data Redundancy: Replicating data for security, compliance, and continuity purposes.
Data Proximity: Bringing data closer to distant teams or customers for faster access.
Maintaining a redundant copy of your data sounds, well, redundant, but it is the most common use case for cloud replication. It supports disaster recovery as part of a broad cyber resilience framework, reduces the risk of downtime, and helps you comply with regulations.
Four Levels of Testing: Unit, Integration, System, and Acceptance
Friendly reminder to both drink and code responsibly (and probably not at the same time).
The Most Interesting Man in the World may test his code in production, but most of us prefer to lead a somewhat less “interesting” life. If you work in software development, you are likely well aware of the various types of testing, but it’s useful to review them to see how different tests might interact with data in cloud object storage.
Let’s consider a photo storage service that stores images in a Backblaze B2 Bucket. There are several real-world Backblaze customers that do exactly this, including Can Stock Photo and CloudSpot, but we’ll just imagine some of the features that any photo storage service might provide that its developers would need to write tests for.
Unit Tests
Unit tests test the smallest components of a system. For example, our photo storage service will contain code to manipulate images in a B2 Bucket, so its developers will write unit tests to verify that each low-level operation completes successfully. A test for thumbnail creation, for example, might do the following:
Directly upload a test image to the bucket.
Run the “‘Create Thumbnail” function against the test image.
Verify that the resulting thumbnail image has indeed been created in the expected location in the bucket with the expected dimensions.
Delete both the test and thumbnail images.
A large application might have hundreds, or even thousands, of unit tests, and it’s not unusual for development teams to set up automation to run the entire test suite against every change to the system to help guard against bugs being introduced during the development process.
Typically, unit tests require a blank slate to work against, with test code creating and deleting files as illustrated above. In this scenario, the test automation might create a bucket, run the test suite, then delete the bucket, ensuring a consistent environment for each test run.
Integration Tests
Integration tests bring together multiple components to test that they interact correctly. In our photo storage example, an integration test might combine image upload, thumbnail creation, and artificial intelligence (AI) object detection—all of the functions executed when a user adds an image to the photo storage service. In this case, the test code would do the following:
Run the “Add Image” procedure against a test image of a specific subject, such as a cat.
Verify that the test and thumbnail images are present in the expected location in the bucket, the thumbnail image has the expected dimensions, and an entry has been created in the image index with the “cat” tag.
Delete the test and thumbnail images, and remove the image’s entry from the index.
Again, integration tests operate against an empty bucket, since they test particular groups of functions in isolation, and require a consistent, known environment.
System Tests
The next level of testing, system testing, verifies that the system as a whole operates as expected. System testing can be performed manually by a QA engineer following a test script, but is more likely to be automated, with test software taking the place of the user. For example, the Selenium suite of open source test tools can simulate a user interacting with a web browser. A system test for our photo storage service might operate as follows:
Open the photo storage service web page.
Click the upload button.
In the resulting file selection dialog, provide a name for the image, navigate to the location of the test image, select it, and click the submit button.
Wait as the image is uploaded and processed.
When the page is updated, verify that it shows that the image was uploaded with the provided name.
Click the image to go to its details.
Verify that the image metadata is as expected. For example, the file size and object tag match the test image and its subject.
When we test the system at this level, we usually want to verify that it operates correctly against real-world data, rather than a synthetic test environment. Although we can generate “dummy data” to simulate the scale of a real-world system, real-world data is where we find the wrinkles and edge cases that tend to result in unexpected system behavior. For example, a German-speaking user might name an image “Schloss Schönburg.” Does the system behave correctly with non-ASCII characters such as ö in image names? Would the developers think to add such names to their dummy data?
Non-ASCII characters: our excuse to give you your daily dose of seratonin. Source.
Acceptance Tests
The final testing level, acceptance testing, again involves the system as a whole. But, where system testing verifies that the software produces correct results without crashing, acceptance testing focuses on whether the software works for the user. Beta testing, where end-users attempt to work with the system, is a form of acceptance testing. Here, real-world data is essential to verify that the system is ready for release.
How Does Cloud Replication Fit Into Testing Environments?
Of course, we can’t just use the actual production environment for system and acceptance testing, since there may be bugs that destroy data. This is where Cloud Replication comes in: we can create a replica of the production environment, complete with its quirks and edge cases, against which we can run tests with no risk of destroying real production data. The term staging environment is often used in connection with acceptance testing, with test(ing) environments used with unit, integration, and system testing.
Caution: Be Aware of PII!
Before we move on to look at how you can put replication into practice, it’s worth mentioning that it’s essential to determine whether you should be replicating the data at all, and what safeguards you should place on replicated data—and to do that, you’ll need to consider whether or not it is or contains personally identifiable information (PII).
The National Institute of Science and Technology (NIST) document SP 800-122 provides guidelines for identifying and protecting PII. In our example photo storage site, if the images include photographs of people that may be used to identify them, then that data may be considered PII.
In most cases, you can still replicate the data to a test or staging environment as necessary for business purposes, but you must protect it at the same level that it is protected in the production environment. Keep in mind that there are different requirements for data protection in different industries and different countries or regions, so make sure to check in with your legal or compliance team to ensure everything is up to standard.
In some circumstances, it may be preferable to use dummy data, rather than replicating real-world data. For example, if the photo storage site was used to store classified images related to national security, we would likely assemble a dummy set of images rather than replicating production data.
How Does Backblaze Cloud Replication Work?
To replicate data in Backblaze B2, you must create a replication rule via either the web console or the B2 Native API. The replication rule specifies the source and destination buckets for replication and, optionally, advanced replication configuration. The source and destination buckets can be located in the same account, different accounts in the same region, or even different accounts in different regions; replication works just the same in all cases. While standard Backblaze B2 Cloud Storage rates apply to replicated data storage, note that Backblaze does not charge service or egress fees for replication, even between regions.
It’s easier to create replication rules in the web console, but the API allows access to two advanced features not currently accessible from the web console:
Setting a prefix to constrain the set of files to be replicated.
Excluding existing files from the replication rule.
Don’t worry: this blog post provides a detailed explanation of how to create replication rules via both methods.
Once you’ve created the replication rule, files will begin to replicate at midnight UTC, and it can take several hours for the initial replication if you have a large quantity of data. Files uploaded after the initial replication rule is active are automatically replicated within a few seconds, depending on file size. You can check whether a given file has been replicated either in the web console or via the b2-get-file-info API call. Here’s an example using curl at the command line:
In the example response, replicationStatus returns the response pending; once the file has been replicated, it will change to completed.
Here’s a short Python script that uses the B2 Python SDK to retrieve replication status for all files in a bucket, printing the names of any files with pending status:
import argparse
import os

from dotenv import load_dotenv

from b2sdk.v2 import B2Api, InMemoryAccountInfo
from b2sdk.replication.types import ReplicationStatus

# Load credentials from .env file into environment
load_dotenv()

# Read bucket name from the command line
parser = argparse.ArgumentParser(description='Show files with "pending" replication status')
parser.add_argument('bucket', type=str, help='a bucket name')
args = parser.parse_args()

# Create B2 API client and authenticate with key and ID from environment
b2_api = B2Api(InMemoryAccountInfo())
b2_api.authorize_account("production", os.environ["B2_APPLICATION_KEY_ID"], os.environ["B2_APPLICATION_KEY"])

# Get the bucket object
bucket = b2_api.get_bucket_by_name(args.bucket)

# List all files in the bucket, printing names of files that are pending replication
for file_version, folder_name in bucket.ls(recursive=True):
    if file_version.replication_status == ReplicationStatus.PENDING:
        print(file_version.file_name)
Note: Backblaze B2’s S3-compatible API (just like Amazon S3 itself) does not include replication status when listing bucket contents—so for this purpose, it’s much more efficient to use the B2 Native API, as used by the B2 Python SDK.
You can pause and resume replication rules, again via the web console or the API. No files are replicated while a rule is paused. After you resume replication, newly uploaded files are replicated as before. Assuming that the replication rule does not exclude existing files, any files that were uploaded while the rule was paused will be replicated in the next midnight-UTC replication job.
How to Replicate Production Data for Testing
The first question is: does your system and acceptance testing strategy require read-write access to the replicated data, or is read-only access sufficient?
Read-Only Access Testing
If read-only access suffices, it might be tempting to create a read-only application key to test against the production environment, but be aware that testing and production make different demands on data. When we run a set of tests against a dataset, we usually don’t want the data to change during the test. That is: the production environment is a moving target, and we don’t want the changes that are normal in production to interfere with our tests. Creating a replica gives you a snapshot of real-world data against which you can run a series of tests and get consistent results.
It’s straightforward to create a read-only replica of a bucket: you just create a replication rule to replicate the data to a destination bucket, allow replication to complete, then pause replication. Now you can run system or acceptance tests against a static replica of your production data.
To later bring the replica up to date, simply resume replication and wait for the nightly replication job to complete. You can run the script shown in the previous section to verify that all files in the source bucket have been replicated.
Read-Write Access Testing
Alternatively, if, as is usually the case, your tests will create, update, and/or delete files in the replica bucket, there is a bit more work to do. Since testing intends to change the dataset you’ve replicated, there is no easy way to bring the source and destination buckets back into sync—changes may have happened in both buckets while your replication rule was paused.
In this case, you must delete the replication rule, replicated files, and the replica bucket, then create a new destination bucket and rule. You can reuse the destination bucket name if you wish since, internally, replication status is tracked via the bucket ID.
Always Test Your Code in an Environment Other Than Production
In short, we all want to lead interesting lives—but let’s introduce risk in a controlled way, by testing code in the proper environments. Cloud Replication lets you achieve that end while remaining nimble, which means you get to spend more time creating interesting tests to improve your product and less time trying to figure out why your data transformed in unexpected ways.
Now you have everything you need to create test and staging environments for applications that use Backblaze B2 Cloud Object Storage. If you don’t already have a Backblaze B2 account, sign up here to receive 10GB of storage, free, to try it out.
Projects and technologies come and go, and with each new tool comes new workflow changes. But changing the way you move media around can be tough. Maybe you’ve always done things a certain way, and using a new tool feels like too much of a learning curve especially when you’re pressed for time. But the way you’ve always done things isn’t always the best, easiest, or fastest way. Sometimes you need to change the status quo to level up your media operations.
As a freelance editor, I worked on a recent project that presented some challenges that demanded new approaches to media storage challenges you might also be facing. I solved them with the cloud—but not an all-in-one cloud. My solution was a mix of cloud tools, including Adobe Premiere Pro, which gives me customization and flexibility—the best of all worlds in media workflows.
Right Opportunity at the Right Time
Last year I had the opportunity to serve as a digital imaging technician (DIT) on the set of an indie film titled “Vengeance” produced by Falcon Pictures. The role of a DIT can vary. In many instances you’re simply a data wrangler making backups of the data being shot. In others, you work in the color space of the project creating color corrected dailies on set. For “Vengeance”, I was mostly data wrangling.
“Vengeance” was an 11-day shoot in the mountains of Northern California near Bass Lake. While the rest of the crew spent their days hiking around with equipment, I was stationed back at home base with my DIT cart. With a lot of free time, I found myself logging data as it came in. Logging clip names soon turned into organizing bins and prepping the project for editing. And, while I was not the editor on the project, I was happy to help edit while I was on set.
The Challenge
A few months after my work as DIT ended, it became clear that “Vengeance” needed a boost in post-production. The editing was a bit stuck—they had no assistant editor to complete logging and to sound sync all the footage. So, I was asked to help out. The only problem: I needed to be able to share my work with another editor who lived 45 miles away.
Editing “Vengeance” in Adobe Premiere Pro.
Evaluating the World of Workflows and Cloud Tools
So we began to evaluate a few different solutions. It was clear that Adobe Premiere Pro would be used, but data storage was still a big question. We debated a few methods for sharing media:
The traditional route: Sharing a studio. With the other editor 45 miles away, commuting and scheduling time with each other was going to be cumbersome.
Email: We could email project files back and forth as we worked, but how would we keep track of versioning? Project bloat was a big concern.
Sharing a shuttle drive. Or what I’m calling “Sneakernet 2.0.” This is a popular method, but far from efficient.
Google Drive or Dropbox: Another popular option, but also one that comes with costs and service limitations like rate limiting.
None of these options were great, so we went back to the drawing board.
The Solution: A Hybrid Workflow Designed for Our Needs
To come to a final decision for this workflow, we made a list of our needs:
The ability to share a Premiere Pro project file for updates.
The ability to share media for the project.
No exchanging external hard drives.
No driving (a car).
Changes need to be real time.
Based on those needs, here’s where we landed.
Sharing Project Files
Adobe recently released a new update to its Team Projects features within Premiere Pro. Team Projects allows you to host a Premiere Pro project in the Adobe cloud and share it with other Adobe Creative Cloud users. This gave us the flexibility to share a single project and share updates in real time. This means no emailing of project files, versioning issues, or bloated files. That left the issues of the media. How do we share media?
Sharing Media Files
You may think that it would be obvious to share files in the Adobe Creative Cloud where you get 100GB free. And while 100GB may be enough storage for .psd and .ai files, 100GB is nothing for video, especially when we are talking about RED (.r3d) files which start off as approximately 4GB chunks and can quickly add up to terabytes of footage.
So we put everything in a Backblaze B2 Bucket. All the .r3d source files went directly from my Synology network attached storage (NAS) into a Backblaze B2 Bucket using the Synology Cloud Sync tool. In addition to the source files, I used Adobe Media Encoder to generate proxy files of all the .r3d files. This folder of proxy files also synced with Backblaze automatically.
Making Changes in Real Time
What was great about this solution is that all of the uploading is done automatically via a seamless Backblaze + Synology integration, and the Premiere Pro Team Project had a slew of publish functions perfect for real-time updates. And because the project files and proxies are stored in the cloud, I could get to them from several computers. I spent time at my desktop PC logging and syncing footage, but was also able to move to my couch and do the same from my MacBook Pro. I never had to move hard drives around, copy projects files, or worry about version control.
The other editor was able to connect to my Backblaze B2 Bucket using Cyberduck, a cloud storage browser for Mac. Using Cyberduck, he was able to pull down all the proxy files I created and share any files that he created. So, we were synced for the entire duration of the project.
Once the technology was configured, I was able to finish logging for “Vengeance”, sync all the sound, build out stringouts and assemblies, and even a rough cut of every scene for the entire movie, giving the post-production process the boost it needed.
The Power of Centralized Storage for Media Workflows
Technology is constantly evolving, and, in most circumstances, technology makes how we work a lot easier. For years filmmakers have worked on projects by physically moving our source material, whether it was on film reels, tapes, or hard drives. The cloud changed all that.
The key to getting “Vengeance” through post-production was our centralized approach to file management. Files existed in Backblaze already, we simply brought Premiere Pro to the data rather than moving the huge amount of files to Premiere Pro via the Creative Cloud.
The mix of technologies lets us create a customized flow that works for us. Creative Cloud had the benefit of providing a project sharing mechanism, and Backblaze provided a method of sharing media (Synology and Cyberduck) regardless of the tooling each editor had.
Once we hit picture lock, the centralized files will serve as a distribution point for VFX, color, and sound, making turnover a breeze. It can even be used as a distribution hub—check out how American Public Television uses Backblaze to distribute their finished assets.
Centralizing in the cloud not only made it easy for me to work from home, it allowed us to collaborate on a project with ease eliminating the overhead of driving, shuttle drive delivery (Sneakernet 2.0), and version control. The best part? A workflow like this is affordable for any size production and can be set up in minutes.
Have you recently moved to a cloud workflow? Let us know what you’re using and how it went in the comments.
When you’re working hard on an IT or development project, you need to be able to find instructions about the tools you’re using quickly. And, it helps if those instructions are easy to use, easy to understand, and easy to share.
On the Technical Publications team, we spend a lot of time thinking about how to make our docs just that—easy.
The documentation portal has been completely overhauled to deliver on-demand content with a modern look and feel. Whether you’re a developer, web user, or someone who wants to understand how our products and services work, our portal is designed to be user-friendly, with a clean and intuitive interface that makes it easy to navigate and find the information you need.
Here are some highlights of what you can look forward to:
New and updated articles right on the landing page—so you’re always the first to know about important content changes.
A powerful search engine to help you find topics quickly.
A more logical navigation menu that organizes content into sections for easy browsing.
Information about all of the Backblaze B2 features and services in the About section.
You can get started using the Backblaze UI quickly to create application keys, create buckets, manage your files, and more. If you’re programmatically managing your data, we’ve included resources such as SDKs, developer quick-start guides, and step-by-step integration guides.
Perhaps the most exciting enhancement is our API documentation. This resource provides endpoints, parameters, and responses for all three of our APIs: S3-Compatible, B2 Native, and Partner API.
For Fun: A Brief History of Technical Documentation
As our team put our heads together to think about how to announce the new portal, we went down some internet rabbit holes on the history of technical documentation. Technical documentation was recognized as a profession around the start of World War II when technical documents became a necessity for military purposes. (Note: This was also the same era that a “computer” referred to a job for a person, meaning “one who computes”.) But the first technical content in the Western world can be traced back to 1650 B.C—the Rhind Papyrus describes some of the mathematical knowledge and methods of the Egyptians. And the title of first Technical Writer? That goes to none other than poet Geoffrey Chaucer of Canterbury Tales fame for his lesser-known work “A Treatise on the Astrolabe”—a tool that measures angles to calculate time and determine latitude.
After that history lesson, we ourselves waxed a bit poetic about the “old days” when we wrote long manuals in word processing software that were meant to be printed, compiled long indexes for user guides using desktop publishing tools, and wrote more XML code in structured authoring programs than actual content. These days we use what-you-see-is-what-you-get (WYSIWYG) editors in cloud-based content management systems which make producing content much easier and quicker—and none of us are dreaming in HTML anymore.
<section><p>Or maybe we are.</p></section>
Overall, the history of documentation in the tech industry reflects the changing needs of users and the progression of technology. It evolved from technical manuals for experts to user-centric, accessible resources for audiences of all levels of technical proficiency.
The Future of Backblaze Technical Documentation Portal
In the coming months, you’ll see even more Backblaze B2 Cloud Storage content including many third-party integration guides. Backblaze Computer Backup documentation will also find a home here in this new portal so that you’ll have a one-stop-shop for all of your Backblaze technical and help documentation needs.
We are committed to providing the best possible customer-focused documentation experience. Explore the portal to see how our documentation can make using Backblaze even easier!
Erasing data from old devices is important, but it doesn’t have to be boring. Sure, you could just encrypt the data, wipe your drive, and so on, but you can also physically destroy a drive in a myriad of exciting ways. In honor of the United State’s favorite day to celebrate with explosives, let’s talk about not-so-standard ways to get rid of old data (permanently).
Know Your Device
Effective data destruction starts with good planning. When you’re looking at how to securely erase your data, there are different options for hard disk drives (HDDs) and solid state drives (SSDs).
With an HDD, spinning disks are encased in a steel enclosure. In order to do sufficient levels of damage, it’s helpful to get through this steel layer first. Once you’re in, you can drill holes in it, wash it in acid, or shred it.
With an SSD, it’s not just recommended to get through that steel layer, it’s almost essential. SSDs are more resilient because data is stored magnetically. So, pull out that screwdriver, shuck that drive like an oyster, and expose your SSD. If you’re going the physical destruction route, make sure that you’re shredding with a narrow enough width that no forensic scientist can humpty-dumpty your data together again.
Have a Blast
We do have a Sr. Infrastructure Software Engineer who’s gone on record recommending explosives. Note that while we don’t doubt the efficacy, we can’t recommend this option. On the other hand, we’re big fans of bots that smash things.
Destroy Responsibly
We could be accused of overcomplicating things. It’s very effective to wipe your device, or just encrypt your data. Here’s a list of some more extensive articles on the subject that include those options:
Recently, artificial intelligence has been having a moment: It’s gone from an abstract idea in a sci-fi movie, to an experiment in a lab, to a tool that is impacting our everyday lives. With headlines from Bing’s AI confessing its love to a reporter to the struggles over who’s liable in an accident with a self-driving car, the existential reality of what it means to live in an era of rapid technological change is playing out in the news.
The headlines may seem fun, but it’s important to consider what this kind of tech means. In some ways, you can draw a parallel to the birth of the internet, with all the innovation, ethical dilemmas, legal challenges, excitement, and chaos that brought with it. (We’re totally happy to discuss in the comments section.)
So, let’s keep ourselves grounded in fact and do a quick rundown of some of the technical terms in the greater AI landscape. In this article, we’ll talk about three basic terms to help you define the playing field: artificial intelligence (AI), machine learning (ML), and deep learning (DL).
What Is Artificial Intelligence (AI)?
If you were to search “artificial intelligence,” you’d see varying definitions. Here are a few from good sources.
From Google, and not Google as in the search engine, but Google in their thought leadership library:
Artificial intelligence is a broad field, which refers to the use of technologies to build machines and computers that have the ability to mimic cognitive functions associated with human intelligence, such as being able to see, understand, and respond to spoken or written language, analyze data, make recommendations, and more.
Although artificial intelligence is often thought of as a system in itself, it is a set of technologies implemented in a system to enable it to reason, learn, and act to solve a complex problem.
From IBM, a company that has been pivotal in computer development since the early days:
At its simplest form, artificial intelligence is a field, which combines computer science and robust datasets, to enable problem-solving. It also encompasses sub-fields of machine learning and deep learning, which are frequently mentioned in conjunction with artificial intelligence. These disciplines are comprised of AI algorithms which seek to create expert systems which make predictions or classifications based on input data.
From Wikipedia, the crowdsourced and scholarly-sourced oversoul of us all:
Artificial intelligence is intelligence demonstrated by machines, as opposed to intelligence displayed by humans or by other animals. “Intelligence” encompasses the ability to learn and to reason, to generalize, and to infer meaning. Example tasks… include speech recognition, computer vision, translation between (natural) languages, as well as other mappings of inputs.
Allow us to give you the Backblaze summary: Each of these sources are saying that artificial intelligence is what happens when computers start thinking (or appearing to think) for themselves. It’s the what. You call a bot you’re training “an AI;” you also call the characteristic of a computer making decisions AI; you call the entire field of this type of problem solving and programming AI.
However, using the term “artificial intelligence” does not define how bots are solving problems. Terms like “machine learning” and “deep learning” are how that appearance of intelligence is created—the complexity of the algorithms and tasks to perform, whether the algorithm learns, what kind of theoretical math is used to make a decision, and so on. For the purposes of this article, you can think of artificial intelligence as the umbrella term for the processes of machine learning and deep learning.
What Is Machine Learning (ML)?
Machine learning (ML) is the study and implementation of computer algorithms that improve automatically through experience. In contrast with AI and in keeping with our earlier terms, AI is when a computer appears intelligent, and ML is when a computer can solve a complex, but defined, task. An algorithm is a set of instructions (the requirements) of a task.
We engage with algorithms all the time without realizing it—for instance, when you visit a site using a URL starting with “https:” your browser is using SSL (or, more accurately in 2023, TLS), a symmetric encryption algorithm that secures communication between your web browser and the site. Basically, when you click “play” on a cat video, your web browser and the site engage in a series of steps to ensure that the site is what it purports to be, and that a third-party can neither eavesdrop on nor modify any of the cuteness exchanged.
Machine learning does not specify how much knowledge the bot you’re training starts with—any task can have more or fewer instructions. You could ask your friend to order dinner, or you could ask your friend to order you pasta from your favorite Italian place to be delivered at 7:30 p.m.
Both of those tasks you just asked your friend to complete are algorithms. The first algorithm requires your friend to make more decisions to execute the task at hand to your satisfaction, and they’ll do that by relying on their past experience of ordering dinner with you—remembering your preferences about restaurants, dishes, cost, and so on.
By setting up more parameters in the second question, you’ve made your friend’s chances of a satisfactory outcome more probable, but there are a ton of things they would still have to determine or decide in order to succeed—finding the phone number of the restaurant, estimating how long food delivery takes, assuming your location for delivery, etc.
I’m framing this example as a discrete event, but you’ll probably eat dinner with your friend again. Maybe your friend doesn’t choose the best place this time, and you let them know you don’t want to eat there in the future. Or, your friend realizes that the restaurant is closed on Mondays, so you can’t eat there. Machine learning is analogous to the process through which your friend can incorporate feedback—yours or the environment’s—and arrive at a satisfactory dinner plan.
Machines Learning to Teach Machines
A real-world example that will help us tie this down is teaching robots to walk (and there are a ton of fun videos on the subject, if you want to lose yourself in YouTube). Many robotics AI experiments teach their robots to walk in simulated, virtual environments before the robot takes on the physical world.
The key is, though, that the robot updates its algorithm based on new information and predicts outcomes without being programmed to do so. With our walking robot friend, that would look like the robot avoiding an obstacle on its own instead of an operator moving a joystick to avoid the obstacle.
There’s an in-between step here, and that’s how much human oversight there is when training an AI. In our dinner example, it’s whether your friend is improving dinner plans from your feedback (“I didn’t like the food.”) or from the environment’s feedback (the restaurant is closed). With our robot friend, it’s whether their operator tells them there is an obstacle, or they sense it on their own. These options are defined as supervised learning and unsupervised learning.
Supervised Learning
An algorithm is trained with labeled input data and is attempting to get to a certain outcome. A good example is predictive maintenance. Here at Backblaze, we closely monitor our fleet of over 230,000 hard drives; every day, we record the SMART attributes for each drive, as well as which drives failed that day. We could feed a subset of that data into a machine learning algorithm, building a model that captures the relationships between those SMART attributes (the input data) and a drive failure (the label). After this training phase, we could test the algorithm and model on a separate subset of data to verify its accuracy at predicting failure, with the ultimate goal of preventing failure by flagging problematic drives based on unlabeled, real-time data.
Unsupervised Learning
An AI is given unlabeled data and asked to identify patterns and probable outcomes. In this case, you’re not asking the bot for an outcome (“Find me an article on AI.”), you’re asking what exists in the dataset (“What types of articles are in this library? What’s the best way to organize this library?”). For example, Google News uses unsupervised learning to categorize articles on the same story from various online news outlets. It recognizes clusters of contemporaneous articles that share key words, and groups them under a suitable heading.
Generative AI: ChatGPT and Bing, DALL-E and Lensa
Most folks’ exposure to AI has been in the form of generative AI. What generative AIs have done that’s revolutionary is to allow us to make a human-speak query to generate “new” material. You can almost think of a generative AI as a DJ with a huge song library—it’s rapidly pulling information from a huge dataset, remixing that information, and presenting you the result.
So, when you ask ChatGPT to write you a story about a spy, they’re going to go back to all the spy text they’ve seen and give you a story based on those patterns. If you ask it to write a story about James Bond, it’s got a more limited dataset with more predictable patterns. If you ask it to write a six sentence paragraph giving you a good spy plot based on James Bond with the main character Oogly Boogly, you might confuse it (or come up with something totally awesome) because “Oogly Boogly” doesn’t really sound like a name you’d see in spy novels.
Obviously We Had ChatGPT Write the Story
And here it is, for your amusement:
In the realm of espionage, Oogly Boogly, a suave and cunning agent, embarks on a high-stakes mission akin to James Bond’s daring escapades. Sent to retrieve a stolen prototype weapon, he finds himself entangled in a web of international intrigue. Posing as a debonair art collector, Oogly infiltrates an extravagant gala hosted by a nefarious arms dealer known only as “The Viper.” With his wit and charm, Oogly seduces the Viper’s right-hand woman, gaining access to the secret underground lair where the weapon is hidden. In a thrilling climax, Oogly engages in a heart-stopping duel with The Viper, narrowly escaping the clutches of death. With the weapon recovered, Oogly delivers a clever one-liner before vanishing into the night, leaving the world in awe of his daring exploits and longing for his next thrilling adventure.
I couldn’t live without knowing the clever one-liner, so I asked ChatGPT: “Based on the previous response, what was Oogly’s clever one-liner?”
As Oogly outwitted The Viper and secured the weapon, he flashed a sly smile and uttered his clever one-liner, “Looks like this snake’s venom has run dry.”
We can only assume that Oogly then put on sunglasses while the CSI: Miami theme started in the background.
As a tool, generative AI certainly has both possibilities and limitations. In order to train an AI, you need huge amounts of data, which can come from various sources—one example is when consumers share data in exchange for free or improved apps or services, as evidenced by some (ahem) surprising photos surfacing from a Roomba.
Also, just to confuse things before we’ve even gotten to defining deep learning: Some people are calling generative AI’s processes “deep machine learning” based on its use of metadata as well as tools like image recognition, and because the algorithms are designed to learn from themselves in order to give you better results in the future.
An important note for generative AI: It’s certainly not out of the question to make your own library of content—folks call that “training” an AI, though it’s usually done on a larger scale. Check out Backblaze Director of Solution Engineers Troy Liljedahl’s article on Stable Diffusion to see why and how you might want to do that.
What Is Deep Learning (DL)?
Deep learning is the process of training an AI for complex decision making. “Wait,” you say. “I thought ML was already solving complex tasks.” And you’re right, but the difference is in orders of magnitude, branching possibilities, assumptions, task parameters, and so on.
To understand the difference between machine learning and deep learning, we’re going to take a brief time-out to talk about programmable logic. And, we’ll start by using our robot friend to help us see how decision making works in a seemingly simple task, and what that means when we’re defining “complex tasks.”
The direction from the operator is something like, “Robot friend, get yourself from the lab to the front door of the building.” Here are some of the possible decisions the robot then has to make and inputs the robot might have to adjust for:
Now?
If yes, then take a step.
If no, then wait.
What are valid reasons to wait?
If you wait, when should you resume the command?
Take a step.
That step could land on solid ground.
Or, there could be a pencil on the floor.
If you step on the pencil, was it inconsequential or do you slip?
If you slip, do you fall?
If you fall, did you sustain damage?
If yes, do you need to call for help?
If not or if it’s minor, get back up.
If you sustained damage but you could get back up, do you proceed or take the time to repair?
If there’s no damage, then take the next step.
First, you’ll have to determine your new position in the room.
Take the next step. All of the first-step possibilities exist, and some new ones, too.
With the same foot or the other foot?
In a straight line or make a turn?
And so on and so forth. Now, take that direction that has parameters—where and how—and get rid of some of them. Your direction for a deep learning AI might be, “Robot, come to my house.” Or, it might be telling the robot to go about a normal day, which means it would have to decide when and how to walk for itself without a specific “walk” command from an operator.
Neural Networks: Logic, Math, and Processing Power
Thus far in the article, we’ve talked about intelligence as a function of decision making. Algorithms outline the decision we want made or the dataset we want the AI to engage with. But, when you think about the process of decision making, you’re actually talking about many decisions getting made in a series. With machine learning, you’re giving more parameters for how to make decisions. With deep learning, you’re asking open-ended questions.
You can certainly view these definitions as having a big ol’ swath of gray area and overlap in their definitions. But at a certain point, all those decisions a computer has to make starts to slow a computer down and require more processing power. There are processors for different kinds of AI by the way, all designed to increase processing power. Whatever that point is, you’ve reached a deep learning threshold.
If we’re looking at things as yes/nos, we assume there’s only one outcome to each choice. Ultimately, yes, our robot is either going to take a step or not. But all of those internal choices, as you can see from the above messy and incomplete list, create nested dependencies. When you’re solving a complex task, you need a structure that is not a strict binary, and that’s when you create a neural network.
Neural networks learn, just like other ML mechanisms. As its name suggests, a neural network is an interlinked network of artificial neurons based on the structure of biological brains. Each neuron processes data from its incoming connections, passing on results to its outgoing connections. As we train the network by feeding it data, the training algorithm adjusts those processes to optimize the output of the network as a whole. Our robot friend may slip the first few times it steps on a pencil, but, each time, it’s fine-tuning its processing with the goal of staying upright.
You’re Giving Me a Complex!
As you can probably tell, training is important, and the more complex the problem, the more time and data you need to train to consider all possibilities. All possibilities necessarily means providing as much data as possible so that an AI can learn what’s relevant to solving a problem and give you a good solution to your question. Frankly, if or when you’ve succeeded, often scientists have difficulty tracking how neural networks make decisions.
That’s not surprising, in some ways. Deep learning has to solve for shades of gray—for the moment when one user would choose one solution and another would use another solution and it’s hard to tell which was the “better” solution between the two. Take natural language models: You’re translating “I want to drive a car” from English to Spanish. Do you include the implied subject—”yo quiero” instead of “quiero”—when both are correct? Do you use “el coche” or “el carro” or “el auto” as your preferred translation of “car”? Great, now do all that for poetry, with its layers of implied meanings even down to using a single word, cultural and historical references, the importance of rhythm, pagination, lineation, etc.
And that’s before we even get to ethics. Just like in the trolley problem, you have to define how you define what’s “better,” and “better” might just change with context. The trolley problem presents you with a scenario: a train is on course to hit and kill people on the tracks. You can change the direction of the train, but you can’t stop the train. You have two choices:
You can do nothing, and the train will hit five people.
You can pull a lever and the train will move to a side track where it will kill one person.
The second scenario is better from a net-harm perspective, but it makes you directly responsible for killing someone. And, things become complicated when you start to add details. What if there are children on the track? Does it matter if the people are illegally on the track? What if pulling the lever also kills you—how much do you/should you value your own survival against other peoples’? These are just the sorts of scenarios that self-driving cars have to solve for.
Deep learning also leaves room for assumptions. In our walking example above, we start with challenging a simple assumption—Do I take the first step now or later? If I wait, how do I know when to resume? If my operator is clearly telling me to do something, under what circumstances can I reject the instruction?
Yeah, But Is AI (or ML or DL) Going to Take Over the World?
Okay, deep breaths. Here’s the summary:
Artificial intelligence is what we call it when a computer appears intelligent. It’s the umbrella term.
Machine learning and deep learning both describe processes through which the computer appears intelligent—what it does. As you move from machine learning to deep learning, the tasks get more complex, which means they take more processing power and have different logical underpinnings.
Our brains organically make decisions, adapt to change, process stimuli—and we don’t really know how—but the bottom line is: it’s incredibly difficult to replicate that process with inorganic materials, especially when you start to fall down the rabbit hole of the overlap between hardware and software when it comes to producing chipsets, and how that material can affect how much energy it takes to compute. And don’t get us started on quantum math.
AI is one of those areas where it’s easy to get lost in the sauce, so to speak. Not only does it play on our collective anxieties, but it also represents some seriously complicated engineering that brings together knowledge from various disciplines, some of which are unexpected to non-experts. (When you started this piece, did you think we’d touch on neuroscience?) Our discussions about AI—what it is, what it can do, and how we can use it—become infinitely more productive once we start defining things clearly. Jump into the comments to tell us what you think, and look out for more stories about AI, cloud storage, and beyond.
Running an industry-standard benchmark, and because AWS is almost five times more expensive, we were expecting to see a trade-off between better performance on the single cloud AWS deployment and lower cost on the multi-cloud Backblaze/Vultr equivalent, but we were very pleasantly surprised by the results we saw.
Spoiler alert: not only was the Backblaze B2 + Vultr combination significantly cheaper than Amazon S3/EC2, it also outperformed the Amazon services by a wide margin. Read on for the details—we cover a lot of background on this experiment, but you can skip straight ahead to the results of our tests if you’d rather get to the good stuff.
First, Some History: The Evolution of Big Data Storage Architecture
Back in 2004, Google’s MapReduce paper lit a fire under the data processing industry, proposing a new “programming model and an associated implementation for processing and generating large datasets.” MapReduce was applicable to many real-world data processing tasks, and, as its name implies, presented a straightforward programming model comprising two functions (map and reduce), each operating on sets of key/value pairs. This model allowed programs to be automatically parallelized and executed on large clusters of commodity machines, making it well suited for tackling “big data” problems involving datasets ranging into the petabytes.
The Apache Hadoop project, founded in 2005, produced an open source implementation of MapReduce, as well as the Hadoop Distributed File System (HDFS), which handled data storage. A Hadoop cluster could comprise hundreds, or even thousands, of nodes, each one responsible for both storing data to disk and running MapReduce tasks. In today’s terms, we would say that each Hadoop node combined storage and compute.
With the advent of cloud computing, more flexible big data frameworks, such as Apache Spark, decoupled storage from compute. Now organizations could store petabyte-scale datasets in cloud object storage, rather than on-premises clusters, with applications running on cloud compute platforms. Fast intra-cloud network connections and the flexibility and elasticity of the cloud computing environment more than compensated for the fact that big data applications were now accessing data via the network, rather than local storage.
Today we are moving into the next phase of cloud computing. With specialist providers such as Backblaze and Vultr each focusing on a core capability, can we move storage and compute even further apart, into different data centers? Our hypothesis was that increased latency and decreased bandwidth would severely impact performance, perhaps by a factor of two or three, but cost savings might still make for an attractive alternative to colocating storage and compute at a hyperscaler such as AWS. The tools we chose to test this hypothesis were the Trino open source SQL Query Engine and the TPC-DS benchmark.
Benchmarking Deployment Options With TPC-DS
The TPC-DS benchmark is widely used to measure the performance of systems operating on online analytical processing (OLAP) workloads, so it’s well suited for comparing deployment options for big data analytics.
A formal TPC-DS benchmark result measures query response time in single-user mode, query throughput in multiuser mode and data maintenance performance, giving a price/performance metric that can be used to compare systems from different vendors. Since we were focused on query performance rather than data loading, we simply measured the time taken for each configuration to execute TPC-DS’s set of 99 queries.
Helpfully, Trino includes a tpcds catalog with a range of schemas each containing the tables and data to run the benchmark at a given scale. After some experimentation, we chose scale factor 10, corresponding to approximately 10GB of raw test data, as it was a good fit for our test hardware configuration. Although this test dataset was relatively small, the TPC-DS query set simulates a real-world analytical workload of complex queries, and took several minutes to complete on the test systems. It would be straightforward, though expensive and time consuming, to repeat the test for larger scale factors.
We generated raw test data from the Trino tpcds catalog with its sf10 (scale factor 10) schema, resulting in 3GB of compressed Parquet files. We then used Greg Rahn’s version of the TPC-DS benchmark tools, tpcds-kit, to generate a standard TPC-DS 99-query script, modifying the script syntax slightly to match Trino’s SQL dialect and data types. We ran the set of 99 queries in single user mode three times on each of three combinations of compute/storage platforms: EC2/S3, EC2/B2 and Vultr/B2. The EC2/B2 combination allowed us to isolate the effect of moving storage duties to Backblaze B2 while keeping compute on Amazon EC2.
A note on data transfer costs: AWS does not charge for data transferred between an Amazon S3 bucket and an Amazon EC2 instance in the same region. In contrast, the Backblaze + Vultr partnership allows customers free data transfer between Backblaze B2 and Vultr Cloud Compute across any combination of regions.
Deployment Options for Cloud Compute and Storage
AWS
The EC2 configuration guide for Starburst Enterprise, the commercial version of Trino, recommends a r4.4xlarge EC2 instance, a memory-optimized instance offering 16 virtual CPUs and 122 GiB RAM, running Amazon Linux 2.
Following this lead, we configured an r4.4xlarge instance with 32GB of gp2 SSD local disk storage in the us-west-1 (Northern California) region. The combined hourly cost for the EC2 instance and SSD storage was $1.19.
We created an S3 bucket in the same us-west-1 region. After careful examination of the Amazon S3 Pricing Guide, we determined that the storage cost for the data on S3 was $0.026 per GB per month.
Vultr
We selected Vultr’s closest equivalent to the EC2 r4.4xlarge instance: a Memory Optimized Cloud Compute instance with 16 vCPUs, 128GB RAM plus 800GB of NVMe local storage, running Debian 11, at a cost of $0.95/hour in Vultr’s Silicon Valley region. Note the slight difference in the amount of available RAM–Vultr’s virtual machine (VM) includes an extra 6GB, despite its lower cost.
Backblaze B2
We created a Backblaze B2 Bucket located in the Sacramento, California data center of our U.S. West region, priced at $0.005/GB/month, about one-fifth the cost of Amazon S3.
Trino Configuration
We used the official Trino Docker image configured identically on the two compute platforms. Although a production Trino deployment would typically span several nodes, for simplicity, time savings, and cost-efficiency we brought up a single-node test deployment. We dedicated 78% of the VM’s RAM to Trino, and configured its Hive connector to access the Parquet files via the S3 compatible API. We followed the Trino/Backblaze B2 getting started tutorial to ensure consistency between the environments.
Benchmark Results
The table shows the time taken to complete the TPC-DS benchmark’s 99 queries. We calculated the mean of three runs for each combination of compute and storage. All times are in minutes and seconds, and a lower time is better.
We used Trino on Amazon EC2 accessing data on Amazon S3 as our starting point; this configuration ran the benchmark in 20:43.
Next, we kept Trino on Amazon EC2 and moved the data to Backblaze B2. We saw a surprisingly small difference in performance, considering that the data was no longer located in the same AWS region as the application. The EC2/B2 Storage Cloud combination ran the benchmark just 38 seconds slower (that’s about 3%), clocking in at 21:21.
When we looked at Trino running on Vultr accessing data on Amazon S3, we saw a significant increase in performance. On Vultr/S3, the benchmark ran in 15:07, 27% faster than the EC2/S3 combination. We suspect that this is due to Vultr providing faster vCPUs, more available memory, faster networking, or a combination of the three. Determining the exact reason for the performance delta would be an interesting investigation, but was out of scope for this exercise.
Finally, looking at Trino on Vultr accessing data on Backblaze B2, we were astonished to see that not only did this combination post the fastest benchmark time of all, Trino on Vultr/Backblaze B2’s time of 12:39 was 16% faster than Vultr/S3 and 39%faster than Trino on EC2/S3!
Note: this is not a formal TPC-DS result, and the query times generated cannot be compared outside this benchmarking exercise.
The Bottom Line: Higher Performance at Lower Cost
For the scale factor 10 TPC-DS data set and queries, with comparably specified instances, Trino running on Vultr retrieving data from B2 is 39% faster than Trino on EC2 pulling data from S3, with 20% lower compute cost and 76% lower storage cost.
You can get started with both Backblaze B2 and Vultr free of charge—click here to sign up for Backblaze B2, with 10GB free storage forever, and click here for $250 of free credit at Vultr.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.