The holidays are fast approaching and with them the many cyber sales that provide both inspiration and opportunity for gift giving on any budget. To help narrow the field, every year I ask my fellow Backblazers to submit the gifts that they are looking forward to both gifting and receiving. (Hopefully some of their loved ones read the blog?) And of course, I’ve sprinkled in a few of my favorites as well. Without further ado, here’s what we suggest looking into for your 2023 gift giving!
This little thing is pretty neat. It helps you keep track of your health, tracking everything from sleep to stress levels. It lasts for a week on a single charge, and is super easy on the eyes, so you’ll want to wear it all over the place.
We have a lot of hikers, joggers, and runners at Backblaze and, as firm believers in thinking about your backup options before a disaster, the Garmin is an awesome-to-have trail buddy.
While a cocktail shaker is a pretty common household item, this one is sure to impress. Ask questions like, “Could my drink possibly get any colder and stay that way?” and “Can I customize my shaker with a sticker of my cat’s face?” And the Yeti’s answer is yes. Also, you know we love when a product comes in red.
Wine anyone? If you or someone in your life is a big wino, older wines are a delicious treat, with a potentially fatal stumbling block: old, crumbly corks. The Durand corkscrew helps take them out with no breakage.
Another one for winos, the Coravin is an incredible wine system that uses tiny needles and argon gas to pour wine into your glass without having to actually open it. I can personally vouch for this one as a single human who has nice wine bottles and often wants a single glass once or twice a week.
Tea time is a dreamy time and this matcha set allows you to make yourself a traditional cup. And if you need some matcha powder for it, this one comes high comes highly recommended: Organic Ceremonial Grade Matcha Powder.
Tea and coffee at a campsite are a must-have, and if you’ve never tried a Jet Boil, this model is easy to use. Also helpful for those times where you lose power and need to make some hot water in a hurry.
Foodies know and love the sous vide method, a.k.a. low temperature, long time (LTLT). If you’re into cooking your food in a hot tub, you’ll be happy to know that this accessory has come down in price dramatically over time. We like this version of a kitchen appliance, but there is certainly a wide world of sous vide gadgets out there if you’re interested.
Love fancy foods but can’t travel to get them? Goldbelly has become the go-to for nationwide delivery of local favorites, and they now do meal kits as well. We’re not going to say you should give up on your standard, probably nutritionally balanced Hello Freshes of the world, but we will say that these are a whole lot more, well, iconic.
Have your own mini-garden whether you’re in a house or an apartment. With just a little bit of counter space, a semi-green thumb, some patience, and water, you’ll never have herbs go bad in your fridge again.
Not since the times of the Game Boy Advance or maybe the Nintendo 3DS have handheld gaming systems seen such a rise in popularity. Along with the Nintendo Switch, these three handhelds bring the power of a computer to your fingertips on the go. While it’s not quite a gaming rig, it’s good enough for most airline flights, and hey…they’ll all play Baldur’s Gate 3.
It’s a great time to be a nerd. Critical Role, Dimension 20, The Adventure Zone, and many more role playing games (RPGs) are super popular nowadays, and it’s high time you take part. Get the D&D starter kit, some dice, and your soon-to-be best friends, create your character and get rolling.
Backblaze is based in California, but that doesn’t mean that we don’t know about weather. (What’s this wet stuff falling from the sky again?) That said, as a Midwesterner by heritage (dontcha know), I know something about staying warm. Heated clothes take the benefits of your favorite heated blanket and give them to you on the go.
We’re all about being good community members, and this local (to us) company makes hats, fanny packs, and bomber jackets using environmentally friendly materials. They’re good products, in more ways than one.
Studies have shown that meditation has measurable benefits for your mind and body. There are a plethora of tools out there to help you build good habits (see below), but this one is stinkin’ cute. Let this little guy help visually take you through a guided meditation. Bonus: it’s a great gift for kids, too.
The Calm app helps people stay mindful with everything from guided meditation to celebrity-read stories. We’re big fans of their social posts that just encourage you to take a 15 second break—it’s a positive interruption to the doomscroll effect, and a great way to preview some of the app’s content.
A twist on photo frames: you can send pictures to it and have all of your favorite memories staring back at you when you look over. Or, send photos to anyone, anywhere. Definitely some potential prank opportunities to be had; but it’s also a great way to keep in touch with far-flung family members.
Sonos surround systems are a great addition to homes. Multiple speakers can sync up to make sure that you’re never far away from rocking out to Weird Al, no matter where you are in the house.
For the audiophiles in your life, the AirPods Max are the over-the-ear variant of the traditional AirPod. They’re much harder to lose, giving you that impressive combo of sound and noise cancellation you’ve come to expect.
To balance the scales for our Android lovers, here are Google’s in-ear buds. They have a lot of bells and whistles including noise cancellation and built-in Android Assistant. Now when you talk to yourself, someone will answer. (That’s a good thing right?).
LEGO
LEGO is having a bit of a moment (at least in my family) and we have spent a lot of time building complicated models. For the adults in your life that love to tinker, we recommend some of these cool sets!
And, of course, we’d be remiss if we didn’t remind you that Backblaze Computer Backup makes a great gift. Help your family and friends experience the sweet, sweet peace of mind that comes from a good backup strategy and make sure they never lose a file again. Bonus: you don’t even have to go to the store to get it.
Go Forth and Gift!
We hope this guide sparked some ideas and simplified some choices. We’ll also be publishing our second-annual book guide in December if you’re struggling with something for the literary folks in your life. (There’s some good stuff in the first one too.) We love hearing about what folks are excited about, so feel free to give us some more good options in the comments below.
At the end of Q3 2023, Backblaze was monitoring 263,992 hard disk drives (HDDs) and solid state drives (SSDs) in our data centers around the world. Of that number, 4,459 are boot drives, with 3,242 being SSDs and 1,217 being HDDs. The failure rates for the SSDs are analyzed in the SSD Edition: 2023 Drive Stats review.
That leaves us with 259,533 HDDs that we’ll focus on in this report. We’ll review the quarterly and lifetime failure rates of the data drives as of the end of Q3 2023. Along the way, we’ll share our observations and insights on the data presented, and, for the first time ever, we’ll reveal the drive failure rates broken down by data center.
Q3 2023 Hard Drive Failure Rates
At the end of Q3 2023, we were managing 259,533 hard drives used to store data. For our review, we removed 449 drives from consideration as they were used for testing purposes, or were drive models which did not have at least 60 drives. This leaves us with 259,084 hard drives grouped into 32 different models.
The table below reviews the annualized failure rate (AFR) for those drive models for the Q3 2023 time period.
Notes and Observations on the Q3 2023 Drive Stats
The 22TB drives are here: At the bottom of the list you’ll see the WDC 22TB drives (model: WUH722222ALE6L4). A Backblaze Vault of 1,200 drives (plus four) is now operational. The 1,200 drives were installed on September 29, so they only have one day of service each in this report, but zero failures so far.
The old get bolder: At the other end of the time-in-service spectrum are the 6TB Seagate drives (model: ST6000DX000) with an average of 101 months in operation. This cohort had zero failures in Q3 2023 with 883 drives and a lifetime AFR of 0.88%.
Zero failures: In Q3, six different drive models managed to have zero drive failures during the quarter. But only the 6TB Seagate, noted above, had over 50,000 drive days, our minimum standard for ensuring we have enough data to make the AFR plausible.
One failure: There were four drive models with one failure during Q3. After applying the 50,000 drive day metric, two drives stood out:
WDC 16TB (model: WUH721816ALE6L0) with a 0.15% AFR.
Toshiba 14TB (model: MG07ACA14TEY) with a 0.63% AFR.
The Quarterly AFR Drops
In Q3 2023, quarterly AFR for all drives was 1.47%. That was down from 2.2% in Q2 and also down from 1.65% a year ago. The quarterly AFR is based on just the data in that quarter, so it can often fluctuate from quarter to quarter.
In our Q2 2023 report, we suspected the 2.2% for the quarter was due to the overall aging of the drive fleet and in particular we pointed a finger at specific 8TB, 10TB, and 12TB drive models as potential culprits driving the increase. That prediction fell flat in Q3 as nearly two-thirds of drive models experienced a decreased AFR quarter over quarter from Q2 and any increases were minimal. This included our suspect 8TB, 10TB, and 12TB drive models.
It seems Q2 was an anomaly, but there was one big difference in Q3: we retired 4,585 aging 4TB drives. The average age of the retired drives was just over eight years, and while that was a good start, there’s another 28,963 4TB drives to go. To facilitate the continuous retirement of aging drives and make the data migration process easy and safe we use CVT, our awesome in-house data migration software which we’ll cover at another time.
A Hot Summer and the Drive Stats Data
As anyone should in our business, Backblaze continuously monitors our systems and drives. So, it was of little surprise to us when the folks at NASA confirmed the summer of 2023 as Earth’s hottest on record. The effects of this record-breaking summer showed up in our monitoring systems in the form of drive temperature alerts. A given drive in a storage server can heat up for many reasons: it is failing; a fan in the storage server has failed; other components are producing additional heat; the air flow is somehow restricted; and so on. Add in the fact that the ambient temperature within a data center often increases during the summer months, and you can get more temperature alerts.
In reviewing the temperature data for our drives in Q3, we noticed that a small number of drives exceeded the maximum manufacturer’s temperature for at least one day. The maximum temperature for most drives is 60°C, except for the 12TB, 14TB, and 16TB Toshiba drives which have a maximum temperature of 55°C. Of the 259,533 data drives in operation in Q3, there were 354 individual drives (0.0013%) that exceeded their maximum manufacturer temperature. Of those only two drives failed, leaving 352 drives which were still operational as of the end of Q3.
While temperature fluctuation is part of running data centers and temp alerts like these aren’t unheard of, our data center teams are looking into the root causes to ensure we’re prepared for the inevitability of increasingly hot summers to come.
Will the Temperature Alerts Affect Drive Stats?
The two drives which exceeded their maximum temperature and failed in Q3 have been removed from the Q3 AFR calculations. Both drives were 4TB Seagate drives (model: ST4000DM000). Given that the remaining 352 drives which exceeded their temperature maximum did not fail in Q3, we have left them in the Drive Stats calculations for Q3 as they did not increase the computed failure rates.
Beginning in Q4, we will remove the 352 drives from the regular Drive Stats AFR calculations and create a separate cohort of drives to track that we’ll name Hot Drives. This will allow us to track the drives which exceeded their maximum temperature and compare their failure rates to those drives which operated within the manufacturer’s specifications. While there are a limited number of drives in the Hot Drives cohort, it could give us some insight into whether drives being exposed to high temperatures could cause a drive to fail more often. This heightened level of monitoring will identify any increase in drive failures so that they can be detected and dealt with expeditiously.
New Drive Stats Data Fields in Q3
In Q2 2023, we introduced three new data fields that we started populating in the Drive Stats data we publish: vault_id, pod_id, and is_legacy_format. In Q3, we are adding three more fields into each drive records as follows:
datacenter: The Backblaze data center where the drive is installed, currently one of these values: ams5, iad1, phx1, sac0, and sac2.
cluster_id: The name of a given collection of storage servers logically grouped together to optimize system performance. Note: At this time the cluster_id is not always correct, we are working on fixing that.
pod_slot_num: The physical location of a drive within a storage server. The specific slot differs based on the storage server type and capacity: Backblaze (45 drives), Backblaze (60 drives), Dell (26 drives), or Supermicro (60 drives). We’ll dig into these differences in another post.
With these additions, the new schema beginning in Q3 2023 is:
date
serial_number
model
capacity_bytes
failure
datacenter (Q3)
cluster_id (Q3)
vault_id (Q2)
pod_id (Q2)
pod_slot_num (Q3)
is_legacy_format (Q2)
smart_1_normalized
smart_1_raw
The remaining SMART value pairs (as reported by each drive model)
Now that we have the data center for each drive we can compute the AFRs for the drives in each data center. Below you’ll find the AFR for each of five data centers for Q3 2023.
Notes and Observations
Null?: The drives which reported a null or blank value for their data center are grouped in four Backblaze vaults. David, the Senior Infrastructure Software Engineer for Drive Stats, described the process of how we gather all the parts of the Drive Stats data each day. The TL:DR is that vaults can be too busy to respond at the moment we ask, and since the data center field is nice-to-have data, we get a blank field. We can go back a day or two to find the data center value, which we will do in the future when we report this data.
sac0?: sac0 has the highest AFR of all of the data centers, but it also has the oldest drives—nearly twice as old, on average, versus the next closest in data center, sac2. As discussed previously, drive failures do seem to follow the “bathtub curve”, although recently we’ve seen the curve start out flatter. Regardless, as drive models age, they do generally fail more often. Another factor could be that sac0, and to a lesser extent sac2, has some of the oldest Storage Pods, including a handful of 45-drive units. We are in the process of using CVT to replace these older servers while migrating from 4TB to 16TB and larger drives.
iad1: The iad data center is the foundation of our eastern region and has been growing rapidly since coming online about a year ago. The growth is a combination of new data and customers using our cloud replication capability to automatically make a copy of their data in another region.
Q3 Data: This chart is for Q3 data only and includes all the data drives, including those with less than 60 drives per model. As we track this data over the coming quarters, we hope to get some insight into whether different data centers really have different drive failure rates, and, if so, why.
Lifetime Hard Drive Failure Rates
As of September 30, 2023, we were tracking 259,084 hard drives used to store customer data. For our lifetime analysis, we collect the number of drive days and the number of drive failures for each drive beginning from the time a drive was placed into production in one of our data centers. We group these drives by model, then sum up the drive days and failures for each model over their lifetime. That chart is below.
One of the most important columns on this chart is the confidence interval, which is the difference between the low and high AFR confidence levels calculated at 95%. The lower the value, the more certain we are of the AFR stated. We like a confidence interval to be 0.5% or less. When the confidence interval is higher, that is not necessarily bad, it just means we either need more data or the data is somewhat inconsistent.
The table below contains just those drive models which have a confidence interval of less than 0.5%. We have sorted the list by drive size and then by AFR.
The 4TB, 6TB, 8TB, and some of the 12TB drive models are no longer in production. The HGST 12TB models in particular can still be found, but they have been relabeled as Western Digital and given alternate model numbers. Whether they have materially changed internally is not known, at least to us.
One final note about the lifetime AFR data: you might have noticed the AFR for all of the drives hasn’t changed much from quarter to quarter. It has vacillated between 1.39% to 1.45% percent for the last two years. Basically, we have lots of drives with lots of time-in-service so it is hard to move the needle up or down. While the lifetime stats for individual drive models can be very useful, the lifetime AFR for all drives will probably get less and less interesting as we add more and more drives. Of course, a few hundred thousand drives that never fail could arrive, so we will continue to calculate and present the lifetime AFR.
The Hard Drive Stats Data
The complete data set used to create the information used in this review is available on our Hard Drive Stats Data webpage. You can download and use this data for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, and 3) you do not sell this data to anyone; it is free.
Good luck and let us know if you find anything interesting.
What do Sherlock Holmes and ChatGPT have in common? Inference, my dear Watson!
“We approached the case, you remember, with an absolutely blank mind, which is always an advantage. We had formed no theories. We were simply there to observe and to draw inferences from our observations.” —Sir Arthur Conan Doyle, The Adventures of the Cardboard Box
As we all continue to refine our thinking around artificial intelligence (AI), it’s useful to define terminology that describes the various stages of building and using AI algorithms—namely, the AI training stage and the AI inference stage. As we see in the quote above, these are not new concepts: they’re based on ideas and methodologies that have been around since before Sherlock Holmes’ time.
If you’re using AI, building AI, or just curious about AI, it’s important to understand the difference between these two stages so you understand how data moves through an AI workflow. That’s what I’ll explain today.
The TL:DR
The difference between these two terms can be summed up fairly simply: first you train an AI algorithm, then your algorithm uses that training to make inferences from data. To create a whimsical analogy, when an algorithm is training, you can think of it like Watson—still learning how to observe and draw conclusions through inference. Once it’s trained, it’s an inferring machine, a.k.a. Sherlock Holmes.
Whimsy aside, let’s dig a little deeper into the tech behind AI training and AI inference, the differences between them, and why the distinction is important.
Obligatory Neural Network Recap
Neural networks have emerged as the brainpower behind AI, and a basic understanding of how they work is foundational when it comes to understanding AI.
Complex decisions, in theory, can be broken down into a series of yeses and nos, which means that they can be encoded in binary. Neural networks have the ability to combine enough of those smaller decisions, weigh how they affect each other, and then use that information to solve complex problems. And, because more complex decisions require more points of information to come to a final decision, they require more processing power. Neural networks are one of the most widely used approaches to AI and machine learning (ML).
What Is AI Training?: Understanding Hyperparameters and Parameters
In simple terms, training an AI algorithm is the process through which you take a base algorithm and then teach it how to make the correct decision. This process requires large amounts of data, and can include various degrees of human oversight. How much data you need has a relationship to the number of parameters you set for your algorithm as well as the complexity of a problem.
We made this handy dandy diagram to show you how data moves through the training process:
As you can see in this diagram, the end result is model data, which then gets saved in your data store for later use.
And hey—we’re leaving out a lot of nuance in that conversation because dataset size, parameter choice, etc. is a graduate-level topic on its own, and usually is considered proprietary information by the companies who are training an AI algorithm. It suffices to say that dataset size and number of parameters are both significant and have a relationship to each other, though it’s not a direct cause/effect relationship. And, both the number of parameters and the size of the dataset affect things like processing resources—but that conversation is outside of scope for this article (not to mention a hot topic in research).
As with everything, your use case determines your execution. Some types of tasks actually see excellent results with smaller datasets and more parameters, whereas others require more data and fewer parameters. Bringing it back to the real world, here’s a very cool graph showing how many parameters different AI systems have. Note that they very helpfully identified what type of task each system is designed to solve:
So, let’s talk about what parameters are with an example. Back in our very first AI 101 post, we talked about ways to frame an algorithm in simple terms:
Machine learning does not specify how much knowledge the bot you’re training starts with—any task can have more or fewer instructions. You could ask your friend to order dinner, or you could ask your friend to order you pasta from your favorite Italian place to be delivered at 7:30 p.m.
Both of those tasks you just asked your friend to complete are algorithms. The first algorithm requires your friend to make more decisions to execute the task at hand to your satisfaction, and they’ll do that by relying on their past experience of ordering dinner with you—remembering your preferences about restaurants, dishes, cost, and so on.
The factors that help your friend make a decision about dinner are called hyperparameters and parameters. Hyperparameters are those that frame the algorithm—they are set outside the training process, but can influence the training of the algorithms. In the example above, a hyperparameter would be how you structure your dinner feedback. Do you thumbs up or down each dish? Do you write a short review? You get the idea.
Parameters are factors that the algorithm derives through training. In the example above, that’s what time you prefer to eat dinner, which restaurants you enjoy after eating, and so on.
When you’ve trained a neural network, there will be heavier weights between various nodes. That’s a shorthand of saying that an algorithm will prefer a path it knows is significant, and if you want to really get nerdy with it, thisarticle is well-researched, has a ton of math explainers for various training methods, and includes some fantastic visuals. For our purposes, here’s one way people visualize a “trained” algorithm:
The “dropout method” is essentially adding weight to the relationships an AI algorithm has found to be significant for the dataset it’s working on. It can then de-prioritize (or sometimes even eliminate) the other relationships.
Once you have a trained algorithm, then you can use it with a reasonable degree of certainty that it will give you good results, and that leads us to inference.
What Is AI Inference?
Once you’ve trained your algorithm, you can send it out in the world to do its job (and make yours easier). When you present a trained AI algorithm with a problem and it gives you an answer, that’s called inference. It’s using the way it was trained to draw conclusions or make predictions, depending on how it was built, and once an algorithm is in the “inference stage”, it’s no longer learning (usually).
Here’s our diagram for how data might move through an inference process:
As you can see, if we want to add more training data to the algorithm, we’d do so as a separate input/output flow. The goal of this process is to output data.
As we’ve seen in the real world, this does not mean that the AI model will give you a perfect answer every time—depending on, for example, the AI’s access to new or current information, the complexity of training, etc., the algorithm might give you a better or worse (more or less accurate) answer. But, it will be able to look at a new piece of information or dataset, and return a response.
When I asked our friend ChatGPT about this, it broke down inference and defined it in relation to the logical underpinnings of different types of algorithms. (As a mere human, how could I resist using inference while writing about inference?) Sure, ChatGPT may be merely mimicking human-like dialogue based on its ingestion of the whole internet, then giving me the most likely answer based on its specialized neural network that predicts the likelihood of the next word in response to my conversational query and without access to data after January 2022, but here’s what our AI friend had to say for itself:
Machine Learning Inference: In machine learning, after a model has been trained on a dataset, it is deployed to make predictions or classifications on new, unseen data. During inference, the model takes the input data, processes it, and produces an output or a prediction based on the patterns and relationships it learned during training. For example, a trained machine learning model might be used to classify images, predict stock prices, or identify spam emails.
Deep Learning Inference: Deep learning, a subfield of machine learning, involves neural networks with multiple layers. In deep learning, inference means feeding an input through a trained deep neural network and obtaining an output. This is commonly used in applications like image recognition, natural language processing, and speech recognition. Inference in deep learning can be computationally intensive, and specialized hardware, such as GPUs and TPUs, are often used to accelerate the process.
Rule-Based Systems Inference: In rule-based AI systems, inference is the process of applying logical rules to make decisions or draw conclusions. These systems use a set of predefined rules and facts to reason and infer new information. For example, in an expert system for medical diagnosis, inference involves applying a set of rules to patient symptoms and medical knowledge to arrive at a diagnosis.
Probabilistic Inference: In probabilistic AI, inference is used to estimate probabilities and uncertainty. Bayesian networks and Markov decision processes are examples of probabilistic models that perform inference to compute probabilities of events or make decisions based on probabilities.
You’ll notice that each of these are saying basically the same thing: the AI algorithm applies its decision-making paradigm to a problem.
Why Stop Learning During the Inference Stage?
In general, it’s important to keep these two stages—training and inference—of an AI algorithm separate for a few reasons:
Efficiency: Training is typically a computationally intensive process, whereas inference is usually faster and less resource-intensive. Separating them allows for efficient use of computational resources.
Generalization: The model’s ability to generalize from training data to unseen data is a key feature. It should not learn from every new piece of data it encounters during inference to maintain this generalization ability.
Reproducibility: When using trained models in production or applications, it’s important to have consistency and reproducibility in the results. If models were allowed to learn during inference, it would introduce variability and unpredictability in their behavior.
There are some specialized AI algorithms that want to continue learning during the inference stage—your Netflix algorithm is a good example, as are self-driving cars, or dynamic pricing models used to set airfare pricing. On the other hand, the majority of problems we’re trying to solve with AI algorithms deliver better decisions by separating these two phases—think of things like image recognition, language translation, or medical diagnosis, for example.
Training vs. Inference (But, Really: Training Then Inference)
To recap: the AI training stage is when you feed data into your learning algorithm to produce a model, and the AI inference stage is when your algorithm uses that training to make inferences from data. Here’s a chart for quick reference:
Training
Inference
Feed training data into a learning algorithm.
Apply the model to inference data.
Produces a model comprising code and data.
Produces output data.
One time(ish). Retraining is sometimes necessary.
Often continuous.
The difference may seem inconsequential at first glance, but defining these two stages helps to show implications for AI adoption particularly with businesses. That is, given that it’s much less resource intensive (and therefore, less expensive), it’s likely to be much easier for businesses to integrate already-trained AI algorithms with their existing systems.
And, as always, we’re big believers in demystifying terminology for discussion purposes. Let us know what you think in the comments, and feel free to let us know what you’re interested in learning about next.
Have you ever felt like you need a dictionary just to understand what tech-savvy folks are talking about? Well, you’re in luck, because we’re about to decode some of the most common jargon of the digital age, one acronym at a time. Welcome to the world of “as a Service” acronyms, where we take the humble alphabet and turn it into a digital buffet.
So, whether you’re SaaS-savvy or PaaS-puzzled, or just someone desperately searching for a little HaaS (Humor as a Service …yeah, we made that one up), you’ve come to the right place. Let’s take a big slurp from this alphabet soup of tech terms.
The One That Started It All: SaaS
SaaS stands for software as a service, and it’s the founding member of the “as a service” nomenclature. (Though, very confusingly, there’s also Sales as a Service—it’s just not shortened to SaaS. Usually.)
Imagine your software as a pizza delivery service. You don’t need to buy all the ingredients, knead the dough, and bake it yourself. Instead, you simply order a slice, and it magically appears on your table (a.k.a. screen). SaaS products are like that, but instead of pizza they serve up everything from messaging to video conferencing to email marketing to …well, really you name it. Which brings us to…
The Kind of Ironic One: XaaS
XaaS stands for, variously, “everything” or “anything” as a service. No one is really sure about the term’s provenance, but it’s a fair guess to say it came into existence when, well, everything started to become a service, probably sometime around the mid-2010s. The thinking is: if it exists in the digital realm, you can probably get it “as a service.”
The Hardware Related Ones: HaaS, IaaS, and PaaS
HaaS (Hardware as a Service): Instead of purchasing hardware yourself, like computers, servers, networking equipment, and other physical infrastructure components, with HaaS, you can lease or rent the equipment for a given period. It would be like renting a pizza kitchen to make your specialty pies specifically for your sister’s wedding or your grandma’s birthday.
IaaS (Infrastructure as a Service): Infrastructure as a service is kind of like hardware as a service, but it comes with some additional goodies thrown in. Instead of renting just the kitchen, you rent the whole restaurant, chair, tables, and servers (no pun intended) included. IaaS delivers virtualized computing resources, like virtual machines, storage (that’s us!), and networking, over the internet.
PaaS (Platform as a Service): Think of PaaS as a step even further than IaaS—you’re not just renting a pizza restaurant, you’re renting a test kitchen where you can develop your award-winning pie. PaaS provides developers the ability to build, manage, and deploy applications with services like development frameworks, databases, and infrastructure management. It’s the ultimate DIY platform for tech enthusiasts.
The Bad One: RaaS
RaaS stands for Ransomware as a Service, and this is one “as a service” variant you don’t want to mess with. Basically, cybercriminals can purchase ransomware just as easily as you would purchase any app on the app store (it’s probably more complicated than that, but you get the general gist). This makes it easy for even the least savvy cybercriminal to get into the ransomware game. Not great.
The Ones That Help With the Last One: BaaS and DRaaS
BaaS (Backup as a Service): Backup as a Service is a cloud-based data protection solution that allows individuals and organizations to back up their data to a remote cloud. (Hey! That’s us too!) Instead of managing on-premises backup infrastructure, users can securely store their data off-site, often on highly redundant and geographically distributed servers.
DRaaS (Disaster Recovery as a Service): DRaaS stands for disaster recovery as a service, and it’s the antidote to RaaS. Of course, you need good backups to begin with, but adding DRaaS allows businesses to ensure specific recovery time objectives (RTOs, FYI) so they can get back up and running in the event they’re attacked by ransomware or there’s a natural disaster at your primary storage location. DRaaS solutions used to be made almost exclusively with the large enterprise in mind, but today, it’s possible to architect a DRaaS solution for your business affordably and easily.
The Analytical One: DaaS
DaaS stands for data as a service, and it’s your data’s personal chauffeur. It fetches the information you need and serves it up on a silver platter. DaaS offers data on-demand, making structured data accessible to users over the internet. It simplifies data sharing and access, often in real-time, without the need for complex data management.
The Development-Focused Ones: CaaS, BaaS (again), and FaaS
CaaS (Containers as a Service): CaaS simplifies the deployment, scaling, and orchestration of containerized applications. It’s the tech version of a literal container ship. The individual containers “ship” individual pieces of software, and a CaaS tool helps carry all of those individual containers. Check out container management software Docker’s logo for a visualization:
It looks more like a whale carrying containers, which is far more adorable, in our opinion.
BaaS (Backend as a Service): It wouldn’t be the first time an acronym has two meanings. BaaS, in this context, provides a backend infrastructure for mobile and web app developers, offering services like databases, user authentication, and APIs.Imagine your own team of digital butlers tending to the back end of your apps. They handle all the behind-the-scenes stuff, so you can focus on making your app shine.
FaaS (Function as a Service): FaaS is a serverless computing model where developers focus on writing and deploying individual functions or code snippets. These functions run in response to specific events, promoting scalability and efficiency in application development. It’s like having a team of tiny, code-savvy robots doing your bidding.
Go Forth and Abbreviate
Now that you’ve sampled all of the flavors the vast “as a service” world has to offer, we hope you’ve gained a clearer understanding of these sometimes confounding terms. So whether you’re a business professional navigating the cloud or just curious about the tech world, you can wield these acronyms with confidence.
Did we miss any? I’m sure. Let us know in the comments.
You don’t always need the absolute fastest cloud storage—your performance requirements depend on your use case, business objectives, and security needs. But still, faster is usually better. And Backblaze just announced innovation on B2 Cloud Storage that delivers a lot more speed: most file uploads will now be up to 30% faster than AWS S3.
Today, I’m diving into all of the details of this performance improvement, how we did it, and what it means for you.
The TL:DR
The Results: Customers who rely on small file uploads (1MB or less) can expect to see 10–30% faster uploads on average based on our tests, all without any change to durability, availability, or pricing.
What Does This Mean for You?
All B2 Cloud Storage customers will benefit from these performance enhancements, especially those who use Backblaze B2 as a storage destination for data protection software. Small uploads of 1MB or less make up about 70% of all uploads to B2 Cloud Storage and are common for backup and archive workflows. Specific benefits of the performance upgrades include:
Secures data in offsite backup faster.
Frees up time for IT administrators to work on other projects.
Decreases congestion on network bandwidth.
Deduplicates data more efficiently.
Veeam® is dedicated to working alongside our partners to innovate and create a united front against cyber threats and attacks. The new performance improvements released by Backblaze for B2 Cloud Storage furthers our mission to provide radical resilience to our joint customers.
Today. The performance upgrades have been fully rolled out across Backblaze’s global data regions.
How We Did It
Prior to this work, when a customer uploaded a file to Backblaze B2, the data was written to multiple hard disk drives (HDDs). Those operations had to be completed before returning a response to the client. Now, we write the incoming data to the same HDDs and also, simultaneously, to a pool of solid state drives (SSDs) we call a “shard stash,” waiting only for the HDD writes to make it to the filesystems’ in-memory caches and the SSD writes to complete before returning a response. Once the writes to HDD are complete, we free up the space from the SSDs so it can be reused.
Since writing data to an SSD is much faster than writing to HDDs, the net result is faster uploads.
That’s just a brief summary; if you’re interested in the technical details (as well as the results of some rigorous testing), read on!
The Path to Performance Upgrades
As you might recall from many Drive Stats blog posts and webinars, Backblaze stores all customer data on HDDs, affectionately termed ‘spinning rust’ by some. We’ve historically reserved SSDs for Storage Pod (storage server) boot drives.
Until now.
That’s right—SSDs have entered the data storage chat. To achieve these performance improvements, we combined the performance of SSDs with the cost efficiency of HDDs. First, I’ll dig into a bit of history to add some context to how we went about the upgrades.
HDD vs. SSD
IBM shipped the first hard drive way back in 1957, so it’s fair to say that the HDD is a mature technology. Drive capacity and data rates have steadily increased over the decades while cost per byte has fallen dramatically. That first hard drive, the IBM RAMAC 350, had a total capacity of 3.75MB, and cost $34,500. Adjusting for inflation, that’s about $375,000, equating to $100,000 per MB, or $100 billion per TB, in 2023 dollars.
Today, the 16TB version of the Seagate Exos X16—an HDD widely deployed in the Backblaze B2 Storage Cloud—retails for around $260, $16.25 per TB. If it had the same cost per byte as the IBM RAMAC 250, it would sell for $1.6 trillion—around the current GDP of China!
SSDs, by contrast, have only been around since 1991, when SanDisk’s 20MB drive shipped in IBM ThinkPad laptops for an OEM price of about $1,000. Let’s consider a modern SSD: the 3.2TB Micron 7450 MAX. Retailing at around $360, the Micron SSD is priced at $112.50 per TB, nearly seven times as much as the Seagate HDD.
So, HDDs easily beat SSDs in terms of storage cost, but what about performance? Here are the numbers from the manufacturers’ data sheets:
Since HDD platters rotate at a constant rate, 7,200 RPM in this case, they can transfer more blocks per revolution at the outer edge of the disk than close to the middle—hence the two figures for the X16’s transfer rate.
The SSD is over 20 times as fast at sustained data transfer than the HDD, but look at the difference in random transfer rates! Even when the HDD is at its fastest, transferring blocks from the outer edge of the disk, the SSD is over 2,200 times faster reading data and nearly 900 times faster for writes.
This massive difference is due to the fact that, when reading data from random locations on the disk, the platters have to complete an average of 0.5 revolutions between blocks. At 7,200 rotations per minute (RPM), that means that the HDD spends about 4.2ms just spinning to the next block before it can even transfer data. In contrast, the SSD’s data sheet quotes its latency as just 80µs (that’s 0.08ms) for reads and 15µs (0.015ms) for writes, between 84 and 280 times faster than the spinning disk.
Let’s consider a real-world operation, say, writing 64kB of data. Assuming the HDD can write that data to sequential disk sectors, it will spin for an average of 4.2ms, then spend 0.25ms writing the data to the disk, for a total of 4.5ms. The SSD, in contrast, can write the data to any location instantaneously, taking just 27µs (0.027ms) to do so. This (somewhat theoretical) 167x speed advantage is the basis for the performance improvement.
Why did I choose a 64kB block? As we mentioned in a recent blog post focusing on cloud storage performance, in general, bigger files are better when it comes to the aggregate time required to upload a dataset. However, there may be other requirements that push for smaller files. Many backup applications split data into fixed size blocks for upload as files to cloud object storage. There is a trade-off in choosing the block size: larger blocks improve backup speed, but smaller blocks reduce the amount of storage required. In practice, backup blocks may be as small as 1MB or even 256kB. The 64kB blocks we used in the calculation above represent the shards that comprise a 1MB file.
The challenge facing our engineers was to take advantage of the speed of solid state storage to accelerate small file uploads without breaking the bank.
Improving Write Performance for Small Files
When a client application uploads a file to the Backblaze B2 Storage Cloud, a coordinator pod splits the file into 16 data shards, creates four additional parity shards, and writes the resulting 20 shards to 20 different HDDs, each in a different Pod.
Note: As HDD capacity increases, so does the time required to recover after a drive failure, so we periodically adjust the ratio between data shards and parity shards to maintain our eleven nines durability target. In the past, you’ve heard us talk about 17 + 3 as the ratio but we also run 16 + 4 and our very newest vaults use a 15 + 5 scheme.
Each Pod writes the incoming shard to its local filesystem; in practice, this means that the data is written to an in-memory cache and will be written to the physical disk at some point in the near future. Any requests for the file can be satisfied from the cache, but the data hasn’t actually been persistently stored yet.
We need to be absolutely certain that the shards have been written to disk before we return a “success” response to the client, so each Pod executes an fsync system call to transfer (“flush”) the shard data from system memory through the HDD’s write cache to the disk itself before returning its status to the coordinator. When the coordinator has received at least 19 successful responses, it returns a success response to the client. This ensures that, even if the entire data center was to lose power immediately after the upload, the data would be preserved.
As we explained above, for small blocks of data, the vast majority of the time spent writing the data to disk is spent waiting for the drive platter to spin to the correct location. Writing shards to SSD could result in a significant performance gain for small files, but what about that 7x cost difference?
Our engineers came up with a way to have our cake and eat it too by harnessing the speed of SSDs without a massive increase in cost. Now, upon receiving a file of 1MB or less, the coordinator splits it into shards as before, then simultaneously sends the shards to a set of 20 Pods and a separate pool of servers, each populated with 10 of the Micron SSDs described above—a “shard stash.” The shard stash servers easily win the “flush the data to disk” race and return their status to the coordinator in just a few milliseconds. Meanwhile, each HDD Pod writes its shard to the filesystem, queues up a task to flush the shard data to the disk, and returns an acknowledgement to the coordinator.
Once the coordinator has received replies establishing that at least 19 of the 20 Pods have written their shards to the filesystem, and at least 19 of the 20 shards have been flushed to the SSDs, it returns its response to the client. Again, if power was to fail at this point, the data has already been safely written to solid state storage.
We don’t want to leave the data on the SSDs any longer than we have to, so, each Pod, once it’s finished flushing its shard to disk, signals to the shard stash that it can purge its copy of the shard.
Real-World Performance Gains
As I mentioned above, that calculated 167x performance advantage of SSDs over HDDs is somewhat theoretical. In the real world, the time required to upload a file also depends on a number of other factors—proximity to the data center, network speed, and all of the software and hardware between the client application and the storage device, to name a few.
The first Backblaze region to receive the performance upgrade was U.S. East, located in Reston, Virginia. Over a 12-day period following the shard stash deployment there, the average time to upload a 256kB file was 118ms, while a 1MB file clocked in at 137ms. To replicate a typical customer environment, we ran the test application at our partner Vultr’s New Jersey data center, uploading data to Backblaze B2 across the public internet.
For comparison, we ran the same test against Amazon S3’s U.S. East (Northern Virginia) region, a.k.a. us-east-1, from the same machine in New Jersey. On average, uploading a 256kB file to S3 took 157ms, with a 1MB file taking 153ms.
So, comparing the Backblaze B2 U.S. East region to the Amazon S3 equivalent, we benchmarked the new, improved Backblaze B2 as 30% faster than S3 for 256kB files and 10% faster than S3 for 1MB files.
These low-level tests were confirmed when we timed Veeam Backup & Replication software backing up 1TB of virtual machines with 256k block sizes. Backing the server up to Amazon S3 took three hours and 12 minutes; we measured the same backup to Backblaze B2 at just two hours and 15 minutes, 40% faster than S3.
Test Methodology
We wrote a simple Python test app using the AWS SDK for Python (Boto3). Each test run involved timing 100 file uploads using the S3 PutObject API, with a 10ms delay between each upload. (FYI, the delay is not included in the measured time.) The test app used a single HTTPS connection across the test run, following best practice for API usage. We’ve been running the test on a VM in Vultr’s New Jersey region every six hours for the past few weeks against both our U.S. East region and its AWS neighbor. Latency to the Backblaze B2 API endpoint averaged 5.7ms, to the Amazon S3 API endpoint 7.8ms, as measured across 100 ping requests.
What’s Next?
At the time of writing, shard stash servers have been deployed to all of our data centers, across all of our regions. In fact, you might even have noticed small files uploading faster already. It’s important to note that this particular optimization is just one of a series of performance improvements that we’ve implemented, with more to come. It’s safe to say that all of our Backblaze B2 customers will enjoy faster uploads and downloads, no matter their storage workload.
The year is 2023, and the human race has spread across the globe. Nuclear powered flying cars are everywhere, and the first colonies have landed on Mars! [Radio crackles.]
Okay, so that isn’t exactly how it’s gone down, but in honor of Halloween, the day celebrates the whimsy of all things being possible, let’s talk about things that used to be science fiction and aren’t anymore.
Artificial Intelligence (AI)
Have we gotten reader fatigue from this topic yet? (As technology people by nature, we’re deep in it.) The rise of generative AI over the past year or so has certainly brought this subject into the spotlight, so in some ways it seems “early” to judge all the ways that AI will change things. On the other hand, there are lots of tools and functions we’ve been using for a while that have been powered by AI algorithms, including AI assistants.
Shout out to this content creator for a hilarious video.
At the risk of not doing this topic justice in this list, I’ll say that there’s plenty of reporting on—and plenty of potential for—AI now and in the future.
Aliens
This year, the U.S. House Oversight Committee was conducting an investigation on unidentified flying objects (UFOs). While many UFOs turn out to be things like weather balloons and drones designed for home use, well, some apparently aren’t. Three military veterans, including a former intelligence officer, went on record saying that the government has a secret facility where it’s been reverse engineering highly advanced vehicles, and that the U.S. has recovered “non-human biologics” from these crash sites. (Whatever that means—but we all know what that means, right…)
Here’s the video, if you want to see for yourself.
Weirdly, the public response was… not much of one. (The last couple of years have been “a year”.) But, chalk this one up as confirmed.
Space Stations
The list of sci-fi shows and books set on space stations is definitely too long to list item by item. Depending on your age (and we won’t ask you to tell us), you may think of Isaac Asimov’s Foundation series (the books), Star Wars, Zenon, Girl of the 21st Century (or maybe the Zequel?), Babylon 5, or the Expanse.
Back in the real world, the International Space Station (ISS) has been in orbit since 1998 and runs all manner of scientific experiments. Notably, these experiments include the Alpha Meter Spectrometer (AMS-02) which is designed to detect things like dark matter and antimatter and solve the fundamental mysteries of the universe. (No big deal.)
For those of us stuck on Earth (for now), you can keep up with the ISS in lots of ways. Check out this map that lets you track whether you can see it from your current location. (Wave the next time it floats over!) And, of course, there are some fun YouTube channels streaming the ISS. Here’s just one:
Universal Translators
Okay, universal translators is the cool sci-fi name, but if you want the actual, machine learning (ML) name, folks call that interlingual machine translation. Translation may seem straightforward at first glance, but, as this legendary Star Trek episode demonstrates, things are not always so simple.
And sure, it’s easy to say that this is an unreasonable standard given that most human languages are known—but are they? Native language reclamation projects like those from the Cherokee and Oneida tribes demonstrate how easy it is to lose the nuance of a language without those who natively speak it. Advanced degrees in poetry translation, like this Masters of Fine Arts from the University of Iowa (go Hawks!), help specialists grapple with and capture the nuance between smell, scent, odor, and stench across different languages. And, add to those challenges that translators also have to contend with the wide array of accents in each language.
With that in mind, it’s pretty amazing that we now have translation devices that can be as small as earbuds. Most still require an internet connection, and some are more effective than others, but it’s safe to say we live in the future, folks. Case in point: I had a wine tasting in Tuscany a few months ago where we used Google Translate exclusively to speak with the winemaker and proprietor.
iPads
“What?” you say. “iPads are so normal!” Sure, now you’re used to touch screens. But, let me present you with this image from a show that is definitely considered science fiction:
Shockingly, not an iPad.
Yes, folks, that’s Captain Jean Luc Picard from Star Trek: The Next Generation. And here’s a later one, from Star Trek: Deep Space Nine.
These are plans for the arboretum, so Keiko is probably dropping some knowledge.
Star Trek wikis describe the details of a Personal Access Display Device, or PADD, including a breakdown of how they changed over time in the series. Uhura even had a “digital clipboard” in the original Star Trek series:
We’d have to revisit the episode to see what this masterful side-eye is about.
And, just for the record, we’ll always have a soft spot in our heart for Chief O’Brien’s love of backups.
Robot Domestic Laborer
If you were ever a fan of this lovely lady—
Rosie the Robot, of course, longtime employee and friend of The Jetsons.
—then you’ll be happy to know that your robot caretaker(s) have arrived. Just as Rosie was often seen using a separate vacuum cleaner, they’re not all integrated into one charming package—yet. If you’re looking for the full suite of domestic help, you’ll have to get a few different products.
First up, the increasingly popular (and, as time goes on, increasingly affordable) robot vacuum. There are tons of models, from the simple vacuum to the vacuum/mop. While they’re reportedly prone to some pretty hilarious (horrific?) accidents, having one or several of these disk-shaped appliances saves lots of folks lots of time. Bonus: just add cat, and you have adorable internet content in the comfort of your own home.
Next up, the Snoo, marketed as a smart bassinet, will track everything baby, then use that data to help said baby sleep. Parents who can afford to buy or rent this item sing its praises, noting that you can swaddle the baby for safety and review the data collected to better care for your child.
And, don’t forget to round out your household with this charming toilet cleaning robot.
Robot Bartenders
In this iconic scene from The Fifth Element, Luc Besson’s 1997 masterpiece, a drunken priest waxes poetic about a perfect being (spoiler: she’s a woman) to a robot bartender. “Do you know what I mean?” the priest asks. The robot shakes its head. “Do you want some more?”
Start at about 2:00 minutes.
These days, you can actually visit robot bartenders in Las Vegas or on Royal Caribbean cruise ships. Or, if you’re looking for a robot bartender that does more than serve up a great Sazerac, you can turn to Brillo, a robot bartender powered by AI who can also engage in complex dialogue.
Please politely ignore that his face is the stuff of nightmares…it’s what’s on the inside (and in the glass) that counts.
And, if leaving your house sounds terrible, don’t worry: you can also get a specialized appliance for your home.
It’s a Good Time to Be Cloud Storage
One thing that all these current (and future) tech developments have in common: you never see them carting something trailing wires. That means (you guessed it!) that they’re definitely using a central data source delivered via wireless network, a.k.a the cloud.
After you’ve done all the work to, say, study an alien life form or design and program the perfect cocktail, you definitely don’t want to do that work twice. And, do you see folks slowing down to schedule a backup? Definitely not. Easy, online, always updating backups are the way to go.
So, we’re not going to say Backblaze Computer Backup makes the list as a sci-fi idea that we’ve made real; we’re just saying that it’s probably one of those things that people leave off-stage, like characters brushing their teeth on a regular basis. And, past or future, we’re here to remind you that you should always back up your data.
Things We Still Want (Get On It, Scientists!)
Everything we just listed is really cool and all, but let’s not forget that we are still waiting for some very important things. Help us out scientists; we really need these:
We feel compelled to add that, despite our jocular tone, the line between science and science fiction has always been something of a thin one. Studies have shown and inventors like Motorola’s Martin Cooper have gone on record pointing to their inspiration in the imaginative works of science fiction.
So, that leaves us standing by for new developments! Let’s see what 2024 brings. Let us know in the comments section what cool tech in your life fits this brief.
Backblaze and HYCU, the fastest-growing leader in multi-cloud data protection as a service (DPaaS) are teaming up to provide businesses a complete backup solution for modern workloads with low-cost scalable infrastructure—a must-have for modern cyber resilience needs.
Read on to learn more about the partnership, how you can benefit from affordable, agile data protection, and a little bit about a relevant ancient poetic art form.
HYCU + Backblaze: The Power of Collaboration
Within HYCU’s DPaaS platform, shared customers can now select Backblaze B2 Cloud Storage—an S3 compatible object storage platform that provides highly durable, instantly available hot storage—as a destination for their HYCU backups.
With more applications in use across the modern data center, visibility and the ability to protect that mission-critical data has never been at more of a premium. Our collaboration with Backblaze now offers joint customers a cost-effective and scalable data protection solution combining the best in backup and recovery with Backblaze’s streamlined and secure cloud storage.
—Subbiah Sundaram, SVP Product, HYCU, Inc.
The Data Sprawl Problem
On average, businesses and organizations have upwards of 200 different sets of data or “data silos” spread across a growing number of applications, databases, and physical locations. This data sprawl isn’t just hard to manage, it opens up more opportunities for cybercriminals to inject ransomware and gain access to systems.
HYCU gives customers the power to protect every byte while also managing all their business critical data in one place. Powered by the world’s first development platform for data protection, HYCU is the only DPaaS platform that can scale to protect all of your data—wherever it resides. Most importantly, it gives customers the ability to recover from disaster almost instantly, keeping them online and in business, with an average recovery time of 10 minutes.
Backblaze and HYCU:
Keeping data safe for all
at one-fifth the cost.
By combining HYCU data protection with Backblaze B2 Storage Cloud, customers can see up to 80% lower costs in comparison to using providers like AWS for their storage, which means that combining the two can be a force multiplier for a businesses’ ability to fully protect their data and scale efficiently and reliably.
Data protection:
Once challenging, now easy—
HYCU and B2.
The partnership offers the following benefits:
Performance: With a 99.9% uptime service level agreement (SLA) and no cold delays or speed premiums, storing data in Backblaze B2 Cloud Storage means joint customers have instant access to their data whenever and wherever they need it.
Affordability: Existing customers can reduce their total cost of ownership by switching backup tiers with interoperable S3 compatible storage, and institutions and businesses who may not have been able to afford hyperscaler-based solutions can now protect their data.
Compliance and Security: With Backblaze B2’s Object Lock feature, the partnership also offers an additional layer of security through data immutability, which protects backups from ransomware and satisfies evolving cyber insurance requirements.
These benefits can prove particularly useful for higher education institutions, schools, state and local governments, nonprofits, and others where maximizing tight budgets is always a priority.
What’s in a Name?
For the poetically minded among our readership (there must be a few of you, right?), you may have noticed a haiku or two above. And that’s not a coincidence.
The humble haiku inspired the name for HYCU. In true poetic fashion, the name serves more than one purpose—it’s also an acronym for “hyperconverged uptime,” making the least amount of letters do the most, as they should.
Making Data Protection Easier
This partnership adds a powerful new data protection option for joint customers looking to affordably back up their data and establish a disaster recovery strategy. And, this is just the beginning. Stay tuned for more from this partnership, including integrations with HYCU’s other data protection offerings in the future.
Interested in getting started? Learn more in our docs.
Availability, time to first byte, throughput, durability—there are plenty of ways to measure “performance” when it comes to cloud storage. But, which measure is best and how should performance factor in when you’re choosing a cloud storage provider? Other than security and cost, performance is arguably the most important decision criteria, but it’s also the hardest dimension to clarify. It can be highly variable and depends on your own infrastructure, your workload, and all the network connections between your infrastructure and the cloud provider as well.
Today, I’m walking through how to think strategically about cloud storage performance, including which metrics matter and which may not be as important for you.
First, What’s Your Use Case?
The first thing to keep in mind is how you’re going to be using cloud storage. After all, performance requirements will vary from one use case to another. For instance, you may need greater performance in terms of latency if you’re using cloud storage to serve up software as a service (SaaS) content; however, if you’re using cloud storage to back up and archive data, throughput is probably more important for your purposes.
For something like application storage, you should also have other tools in your toolbox even when you are using hot, fast, public cloud storage, like the ability to cache content on edge servers, closer to end users, with a content delivery network (CDN).
Ultimately, you need to decide which cloud storage metrics are the most important to your organization. Performance is important, certainly, but security or cost may be weighted more heavily in your decision matrix.
What Is Performant Cloud Storage?
Performance can be described using a number of different criteria, including:
Latency
Throughput
Availability
Durability
I’ll define each of these and talk a bit about what each means when you’re evaluating a given cloud storage provider and how they may affect upload and download speeds.
Latency
Latency is defined as the time between a client request and a server response. It quantifies the time it takes data to transfer across a network.
Latency is primarily influenced by physical distance—the farther away the client is from the server, the longer it takes to complete the request.
If you’re serving content to many geographically dispersed clients, you can use a CDN to reduce the latency they experience.
Latency can be influenced by network congestion, security protocols on a network, or network infrastructure, but the primary cause is generally distance, as we noted above.
Downstream latency is typically measured using time to first byte (TTFB). In the context of surfing the web, TTFB is the time between a page request and when the browser receives the first byte of information from the server. In other words, TTFB is measured by how long it takes between the start of the request and the start of the response, including DNS lookup and establishing the connection using a TCP handshake and TLS handshake if you’ve made the request over HTTPS.
Let’s say you’re uploading data from California to a cloud storage data center in Sacramento. In that case, you’ll experience lower latency than if your business data is stored in, say, Ohio and has to make the cross-country trip. However, making the “right” decision about where to store your data isn’t quite as simple as that, and the complexity goes back to your use case. If you’re using cloud storage for off-site backup, you may wantyour data to be stored farther away from your organization to protect against natural disasters. In this case, performance is likely secondary to location—you only need fast enough performance to meet your backup schedule.
Using a CDN to Improve Latency
If you’re using cloud storage to store active data, you can speed up performance by using a CDN. A CDN helps speed content delivery by caching content at the edge, meaning faster load times and reduced latency.
Edge networks create “satellite servers” that are separate from your central data server, and CDNs leverage these to chart the fastest data delivery path to end users.
Throughput
Throughput is a measure of the amount of data passing through a system at a given time.
If you have spare bandwidth, you can use multi-threading to improve throughput.
Cloud storage providers’ architecture influences throughput, as do their policies around slowdowns (i.e. throttling).
Throughput is often confused with bandwidth. The two concepts are closely related, but different.
To explain them, it’s helpful to use a metaphor: Imagine a swimming pool. The amount of water in it is your file size. When you want to drain the pool, you need a pipe. Bandwidth is the size of the pipe, and throughput is the rate at which water moves through the pipe successfully. So, bandwidth affects your ultimate throughput. Throughput is also influenced by processing power, packet loss, and network topology, but bandwidth is the main factor.
Assuming you have some bandwidth to spare, one of the best ways to improve throughput is to enable multi-threading. Threads are units of execution within processes. When you transmit files using a program across a network, they are being communicated by threads. Using more than one thread (multi-threading) to transmit files is, not surprisingly, better and faster than using just one (although a greater number of threads will require more processing power and memory). To return to our water pipe analogy, multi-threading is like having multiple water pumps (threads) running to that same pipe. Maybe with one pump, you can only fill 10% of your pipe. But you can keep adding pumps until you reach pipe capacity.
When you’re using cloud storage with an integration like backup software or a network attached storage (NAS) device, the multi-threading setting is typically found in the integration’s settings. Many backup tools, like Veeam, are already set to multi-thread by default. Veeam automatically makes adjustments based on details like the number of individual backup jobs, or you can configure the number of threads manually. Other integrations, like Synology’s Cloud Sync, also give you granular control over threading so you can dial in your performance.
Still confused about threads? Learn more in our deep dive, including what’s going on in this diagram.
That said, the gains from increasing the number of threads are limited by the available bandwidth, processing power, and memory. Finding the right setting can involve some trial and error, but the improvements can be substantial (as we discovered when we compared download speeds on different Python versions using single vs. multi-threading).
What About Throttling?
One question you’ll absolutely want to ask when you’re choosing a cloud storage provider is whether they throttle traffic. That means they deliberately slow down your connection for various reasons. Shameless plug here: Backblaze does not throttle, so customers are able to take advantage of all their bandwidth while uploading to B2 Cloud Storage. Amazon and many other public cloud services do throttle.
Upload Speed and Download Speed
Your ultimate upload and download speeds will be affected by throughput and latency. Again, it’s important to consider your use case when determining which performance measure is most important for you. Latency is important to application storage use cases where things like how fast a website loads can make or break a potential SaaS customer. With latency being primarily influenced by distance, it can be further optimized with the help of a CDN. Throughput is often the measurement that’s more important to backup and archive customers because it is indicative of the upload and download speeds an end user will experience, and it can be influenced by cloud storage provider practices, like throttling.
Availability
Availability is the percentage of time a cloud service or a resource is functioning correctly.
Make sure the availability listed in the cloud provider’s service level agreement (SLA) matches your needs.
Keep in mind the difference between hot and cold storage—cold storage services like Amazon Glacier offer slower retrieval and response times.
Also called uptime, this metric measures the percentage of time that a cloud service or resource is available and functioning correctly. It’s usually expressed as a percentage, with 99.9% (three nines) or 99.99% (four nines) availability being common targets for critical services. Availability is often backed by SLAs that define the uptime customers can expect and what happens if availability falls below that metric.
You’ll also want to consider availability if you’re considering whether you want to store in cold storage versus hot storage. Cold storage is lower performing by design. It prioritizes durability and cost-effectiveness over availability. Services like Amazon Glacier and Google Coldline take this approach, offering slower retrieval and response times than their hot storage counterparts. While cost savings is typically a big factor when it comes to considering cold storage, keep in mind that if you do need to retrieve your data, it will take much longer (potentially days instead of seconds), and speeding that up at all is still going to cost you. You may end up paying more to get your data back faster, and you should also be aware of the exorbitant egress fees and minimum storage duration requirements for cold storage—unexpected costs that can easily add up.
Cold
Hot
Access Speed
Slow
Fast
Access Frequency
Seldom or Never
Frequent
Data Volume
Low
High
Storage Media
Slower drives, LTO, offline
Faster drives, durable drives, SSDs
Cost
Lower
Higher
Durability
Durability is the ability of a storage system to consistently preserve data.
Durability is measured in “nines” or the probability that your data is retrievable after one year of storage.
We designed the Backblaze B2 Storage Cloud for 11 nines of durability using erasure coding.
Data durability refers to the ability of a data storage system to reliably and consistently preserve data over time, even in the face of hardware failures, errors, or unforeseen issues. It is a measure of data’s long-term resilience and permanence. Highly durable data storage systems ensure that data remains intact and accessible, meeting reliability and availability expectations, making it a fundamental consideration for critical applications and data management.
We usually measure durability or, more precisely annual durability, in “nines”, referring to the number of nines in the probability (expressed as a percentage) that your data is retrievable after one year of storage. We know from our work on Drive Stats that an annual failure rate of 1% is typical for a hard drive. So, if you were to store your data on a single drive, its durability, the probability that it would not fail, would be 99%, or two nines.
The very simplest way of improving durability is to simply replicate data across multiple drives. If a file is lost, you still have the remaining copies. It’s also simple to calculate the durability with this approach. If you write each file to two drives, you lose data only if both drives fail. We calculate the probability of both drives failing by multiplying the probabilities of either drive failing, 0.01 x 0.01 = 0.0001, giving a durability of 99.99%, or four nines. While simple, this approach is costly—it incurs a 100% overhead in the amount of storage required to deliver four nines of durability.
Erasure coding is a more sophisticated technique, improving durability with much less overhead than simple replication. An erasure code takes a “message,” such as a data file, and makes a longer message in a way that the original can be reconstructed from the longer message even if parts of the longer message have been lost.
The durability calculation for this approach is much more complex than for replication, as it involves the time required to replace and rebuild failed drives as well as the probability that a drive will fail, but we calculated that we could take advantage of erasure coding in designing the Backblaze B2 Storage Cloud for 11 nines of durability with just 25% overhead in the amount of storage required.
How does this work? Briefly, when we store a file, we split it into 16 equal-sized pieces, or shards. We then calculate four more shards, called parity shards, in such a way that the original file can be reconstructed from any 16 of the 20 shards. We then store the resulting 20 shards on 20 different drives, each in a separate Storage Pod (storage server).
Note: As hard disk drive capacity increases, so does the time required to recover after a drive failure, so we periodically adjust the ratio between data shards and parity shards to maintain our eleven nines durability target. Consequently, our very newest vaults use a 15+5 scheme.
If a drive does fail, it can be replaced with a new drive, and its data rebuilt from the remaining good drives. We open sourced our implementation of Reed-Solomon erasure coding, so you can dive into the source code for more details.
In addition to bandwidth and latency, there are a few additional factors that impact cloud storage performance, including:
The size of your files.
The number of files you upload or download.
Block (part) size.
The amount of available memory on your machine.
Small files—that is, those less than 5GB—can be uploaded in a single API call. Larger files, from 5MB to 10TB, can be uploaded as “parts”, in multiple API calls. You’ll notice that there is quite an overlap here! For uploading files between 5MB and 5GB, is it better to upload them in a single API call, or split them into parts? What is the optimum part size? For backup applications, which typically split all data into equal-sized blocks, storing each block as a file, what is the optimum block size? As with many questions, the answer is that it depends.
Remember latency? Each API call incurs a more-or-less fixed overhead due to latency. For a 1GB file, assuming a single thread of execution, uploading all 1GB in a single API call will be faster than ten API calls each uploading a 100MB part, since those additional nine API calls each incur some latency overhead. So, bigger is better, right?
Not necessarily. Multi-threading, as mentioned above, affords us the opportunity to upload multiple parts simultaneously, which improves performance—but there are trade-offs. Typically, each part must be stored in memory as it is uploaded, so more threads means more memory consumption. If the number of threads multiplied by the part size exceeds available memory, then either the application will fail with an out of memory error, or data will be swapped to disk, reducing performance.
Downloading data offers even more flexibility, since applications can specify anyportion of the file to download in each API call. Whether uploading or downloading, there is a maximum number of threads that will drive throughput to consume all of the available bandwidth. Exceeding this maximum will consume more memory, but provide no performance benefit. If you go back to our pipe analogy, you’ll have reached the maximum capacity of the pipe, so adding more pumps won’t make things move faster.
So, what to do to get the best performance possible for your use case? Simple: customize your settings.
Most backup and file transfer tools allow you to configure the number of threads and the amount of data to be transferred per API call, whether that’s block size or part size. If you are writing your own application, you should allow for these parameters to be configured. When it comes to deployment, some experimentation may be required to achieve maximum throughput given available memory.
How to Evaluate Cloud Performance
To sum up, the cloud is increasingly becoming a cornerstone of every company’s tech stack. Gartner predicts that by 2026, 75% of organizations will adopt a digital transformation model predicated on cloud as the fundamental underlying platform. So, cloud storage performance will likely be a consideration for your company in the next few years if it isn’t already.
It’s important to consider that cloud storage performance can be highly subjective and heavily influenced by things like use case considerations (i.e. backup and archive versus application storage, media workflow, or another), end user bandwidth and throughput, file size, block size, etc. Any evaluation of cloud performance should take these factors into account rather than simply relying on metrics in isolation. And, a holistic cloud strategy will likely have multiple operational schemas to optimize resources for different use cases.
Wait, Aren’t You, Backblaze, a Cloud Storage Company?
Why, yes. Thank you for noticing. We ARE a cloud storage company, and we OFTEN get questions about all of the topics above. In fact, that’s why we put this guide together—our customers and prospects are the best sources of content ideas we can think of. Circling back to the beginning, it bears repeating that performance is one factor to consider in addition to security and cost. (And, hey, we would be remiss not to mention that we’re also one-fifth the cost of AWS S3.) Ultimately, whether you choose Backblaze B2 Cloud Storage or not though, we hope the information is useful to you. Let us know if there’s anything we missed.
What do two billion transactions a day look like? Well, the data may be invisible to the naked eye, but the math breaks down to just over 23,000 transactions every second. (Shout out to Kris Allen for burning into my memory that there are 86,400 seconds in a day and my handy calculator!)
Part of my job as a Site Reliability Engineer (SRE) at Backblaze is making sure that greater than 99.9% of those transactions are what we consider “OK” (via status code), and part of the fun is digging for the needle in the haystack of over 7,000 production servers and over 250,000 spinning hard drives to try and understand how all of the different transactions interact with the pieces of infrastructure.
In this blog post, I’m going to pick up where Principal SRE Elliott Sims left off in his 2016 article on load balancing. You’ll notice that the design principles we’ve employed are largely the same (cool!). So, I’ll review our stance on those principles, then talk about how the evolution of the B2 Cloud Storage platform—including the introduction of the S3 Compatible API—has changed our load balancing architecture. Read on for specifics.
Editor’s Note
We know there are a ton of specialized networking terms flying around this article, and one of our primary goals is to make technical content accessible to all readers, regardless of their technical background. To that end, we’ve used footnotes to add some definitions and minimize the disruption to your reading experience.
What Is Load Balancing?
Load balancing is the process of distributing traffic across a network. It helps with resource utilization, prevents overloading any one server, and makes your system more reliable. Load balancers also monitor server health and redirect requests to the most suitable server.
With two billion requests per day to our servers, you can be assured that we use load balancers at Backblaze. Whenever anyone—a Backblaze Computer Backup or a B2 Cloud Storage customer—wants to upload or download data or modify or interact with their files, a load balancer will be there to direct traffic to the right server. Think of them as your trusty mail service, delivering your letters and packages to the correct destination—and using things like zip codes and addresses to interpret your request and get things to the right place.
How Do We Do It?
We build our own load balancers using open-source tools. We use layer 4 load balancing with direct server response (DSR). Here are some of the resources that we call on to make that happen:
Border gateway patrol (BGP) which is part of the Linux kernel1. It’s a standardized gateway protocol that exchanges routing and reachability information on the internet.
keepalived, an open-source routing software. keepalived keeps track of all of our VIPs2 and IPs3 for each backend server.
Hard disk drives (HDDs). We use the same drives that we use for other API servers and whatnot, but that’s definitely overkill—we made that choice to save the work of sourcing another type of device.
A lot of hard work by a lot of really smart folks.
What We Mean by Layers
When we’re talking about layers in load balancing, it’s shorthand for how deep into the architecture your program needs to see. Here’s a great diagram that defines those layers:
DSR takes place at layer 4, but solves the problem presented by a full proxy4 method, having to see the original client’s IP address.
Why Do We Do It the Way We Do It?
Building our own load balancers, instead of buying an off-the-shelf solution, means that we have more control and insight, more cost-effective hardware, and more scalable architecture. In general, DSR is more complicated to set up and maintain, but this method also lets us handle lots of traffic with minimal hardware and supports our goal of keeping data encrypted, even within our own data center.
What Hasn’t Changed
We’re still using a layer 4 DSR approach to load balancing, which we’ll explain below. For reference, other common methods of load balancing are layer 7, full proxy and layer 4, full proxy load balancing.
First, I’ll explain how DSR works. DSR load balancing requires two things:
A load balancer with the VIP address attached to an external NIC5 and ARPing6, so that the rest of the network knows it “owns” the IP.
Two or more servers on the same layer 2 network that also have the VIP address attached to a NIC, either internal or external, but are not replying to ARP requests about that address. This means that no other servers on the network know that the VIP exists anywhere but on the load balancer.
A request packet will enter the network, and be routed to the load balancer. Once it arrives there, the load balancer leaves the source and destination IP addresses intact and instead modifies the destination MAC7 address to that of a server, then puts the packet back on the network. The network switch only understands MAC addresses, so it forwards the packet on to the correct server.
When the packet arrives at the server’s network interface, it checks to make sure the destination MAC address matches its own. The address matches, so the server accepts the packet. The server network interface then, separately, checks to see whether the destination IP address is one attached to it somehow. That’s a yes, even though the rest of the network doesn’t know it, so the server accepts the packet and passes it on to the application. The application then sends a response with the VIP as the source IP address and the client as the destination IP, so the request (and subsequent response) is routed directly to the client without passing back through the load balancer.
So, What’s Changed?
Lots of things. But, since we first wrote this article, we’ve expanded our offerings and platform. The biggest of these changes (as far as load balancing is concerned) is that we added the S3 Compatible API.
We also serve a much more diverse set of clients, both in the size of files they have and their access patterns. File sizes affect how long it takes us to serve requests (larger files = more time to upload or download, which means an individual server is tied up for longer). Access patterns can vastly increase the amount of requests a server has to process on a regular, but not consistent basis (which means you might have times that your network is more or less idle, and you have to optimize appropriately).
So, if we were to update this amazing image from the first article, we might have a tightrope walker with a balancing pole on top of the giraffe, plus some birds flying on a collision course with the elephant.
Where You Can See the Changes: ECMP, Volume of Data Per Month, and API Processing
DSR is how we send data to the customer—the server responds (sends data) directly to the request (client). This is the equivalent of going to the post office to mail something, but adding your home address as the return address (so that you don’t have to go back to the post office to get your reply).
Given how our platform has evolved over the years, things might happen slightly differently. Let’s dig in to some of the details that affect how the load balancers make their decisions—what rules govern how they route traffic, and how different types of requests cause them to behave differently. We’ll look at:
Equal cost multipath routing (ECMP).
Volume of data in petabytes (PBs) per month.
APIs and processing costs.
ECMP
One thing that’s not explicitly outlined above is how the load balancer determines which server should respond to a request. At Backblaze, we use stateless load balancing, which means that the load balancer doesn’t take into account most information about the servers it routes to. We use a round robin approach—i.e. the load balancers choose between one of a few hosts, in order, each time they’re assigning a request.
We also use Maglev, so the load balancers use consistent hashing and connection tracking. This means that we’re minimizing the negative impact of unexpected faults failures from connection-oriented protocols. If a load balancer goes down, its server pool can be transferred to another, and it will make decisions in the same way, seamlessly picking up the load. When the initial load balancer comes back online, it already has a connection to its load balancer friend and can pick up where it left off.
The upside is that it’s super rare to see a disruption, and it essentially only happens when the load balancer and the neighbor host go down in a short period of time. The downside is that the load balancer decision is static. If you have “better” servers for one reason or another—they’re newer, for instance—they don’t take that information into account. On the other hand, we do have the ability to push more traffic to specific servers through ECMP weights if we need to, which means that we have good control over a diverse fleet of hardware.
Volume of Data
Backblaze now has over three exabytes of storage under management. Based on the scalability of the network design, that doesn’t really make a huge amount of difference when you’re scaling your infrastructure properly. What can make a difference is how people store and access their data.
Most of the things that make managing large datasets difficult from an architecture perspective can also be silly for a client. For example: querying files individually (creating lots of requests) instead of batching or creating a range request. (There may be a business reason to do that, but usually, it makes more sense to batch requests.)
On the other hand, some things that make sense for how clients need to store data require architecture realignment. One of those is just a sheer fluctuation of data by volume—if you’re adding and deleting large amounts of data (we’re talking hundreds of terabytes or more) on a “shorter” cycle (monthly or less), then there will be a measurable impact. And, with more data stored, you have the potential for more transactions.
Similarly, if you need to retrieve data often, but not regularly, there are potential performance impacts. Most of them are related to caching, and ironically, they can actually improve performance. The more you query the same “set” of servers for the same file, the more likely that each server in the group will have cached your data locally (which means they can serve it more quickly).
And, as with most data centers, we store our long term data on hard disk drives (HDDs), whereas our API servers are on solid state drives (SSDs). There are positives and negatives to each type of drive, but the performance impact is that data at rest takes longer to retrieve, and data in the cache is on a faster SSD drive on the API server.
On the other hand, the more servers the data center has, the lower the chance that the servers can/will deliver cached data. And, of course, if you’re replacing large volumes of old data with new on a shorter timeline, then you won’t see the benefits. It sounds like an edge case, but industries like security camera data are a great example. While they don’t retrieve their data very frequently, they are constantly uploading and overwriting their data, often to meet different industry requirements about retention periods, which can be challenging to allocate a finite amount of input/output operations per second (IOPS) for uploads, downloads, and deletes.
That said, the built-in benefit of our system is that adding another load balancer is (relatively) cheap. If we’re experiencing a processing chokepoint for whatever reason—typically either a CPU bottleneck or from throughput on the NIC—we can add another load balancer, and just like that, we can start to see bits flying through the new load balancer and traffic being routed amongst more hosts, alleviating the choke points.
APIs and Processing Costs
We mentioned above that one of the biggest changes to our platform was the addition of the S3 Compatible API. When all requests were made through the B2 Native API, the Backblaze CLI tool, or the web UI, the processing cost was relatively cheap.
That’s because of the way our upload requests to the Backblaze Vaults are structured. When you make an upload request via the Native API, there are actually two transactions, one to get an upload URL, and the second to send a request to the Vault. And, all other types of requests (besides upload) have always had to be processed through our load balancers. Since the S3 Compatible API is a single request, we knew we would have to add more processing power and load balancers. (If you want to go back to 2018 and see some of the reasons why, here’s Brian Wilson on the subject—read with the caveat that our current Tech Doc on the subject outlines how we solve the complications he points out.)
We’re still leveraging DSR to respond directly to the client, but we’ve significantly increased the amount of transactions that hit our load balancers, both because it has to take on more of the processing during transit and because, well, lots of folks like to use the S3 Compatible API and our customer base has grown by a quite a bit since 2018.
And, just like above, we’ve set ourselves up for a relatively painless fix: we can add another load balancer to solve most problems.
Do We Have More Complexity?
This is the million dollar question, solved for a dollar: how could we not? Since our first load balancing article, we’ve added features, complexity, and lots of customers. Load balancing algorithms are inherently complex, but we (mostly Elliott and other smart people) have taken a lot of time and consideration to not just build a system that will scale to up and past two billion transactions a day, but that can be fairly “easily” explained and doesn’t require a graduate degree to understand what is happening.
But, we knew it was important early on, so we prioritized building a system where we could “just” add another load balancer. The thinking is more complicated at the outset, but the tradeoff is that it’s simple once you’ve designed the system. It would take a lot for us to outgrow the usefulness of this strategy—but hey, we might get there someday. When we do, we’ll write you another article.
Footnotes
Kernel: A kernel is the computer program at the core of a computer’s operating system. It has control of the system and does things like run processes, manage hardware devices like the hard drive, and handle interrupts, as well as memory and input/output (I/O) requests from software, translating them to instructions for the central processing unit (CPU). ︎
Virtual internet protocol (VIP): An IP address that does not correspond to a real place. ︎
Internet protocol (IP): The global physical address of a device, used to identify devices on the internet. Can be changed. ︎
Proxy: In networking, a proxy is a server application that validates outside requests to a network. Think of them as a gatekeeper. There are several common types of proxies you interact with all the time—HTTPS requests on the internet, for example. ︎
Network interface controller, or network interface card (NIC): This connects the computer to the network. ︎
Address resolution protocol (ARP): The process by which a device or network identifies another device. There are four types. ︎
Media access control (MAC): The local physical address of a device, used to identify devices on the same network. Hardcoded into the device. ︎
Upgrading to a network attached storage (NAS) device puts your data in the digital fast lane. If you’re using one, it’s likely because you want to keep your data close to you, ensuring quick access whenever it’s needed. NAS devices, acting as centralized storage systems connected to local networks, offer a convenient way to access data in just a few clicks.
However, as the volume of data on the NAS increases, its performance can tank. You need to know how to keep your NAS operating at its best, especially with growing data demand.
In this blog, you’ll learn about various factors that can affect NAS performance, as well as practical steps you can take to address these issues, ensuring optimal speed, reliability, and longevity for your NAS device.
Why NAS Performance Matters
NAS devices can function as extended hard disks, virtual file cabinets, or centralized local storage solutions, depending on individual needs.
While NAS offers a convenient way to store data locally, storing the data alone isn’t enough. How quickly and reliably you can access your data can make all the difference if you want an efficient workflow. For example, imagine working on a critical project with your team and facing slow file transfers, or streaming a video on a Zoom call only for it to stutter or buffer continuously.
All these can be a direct result of NAS performance issues, and an increase in stored data can directly undermine the device’s performance. Therefore, ensuring optimal performance isn’t just a technical concern, it’s also a concern that directly affects user experience, productivity, and collaboration.
So, let’s talk about what could potentially cause performance issues and how to enhance your NAS.
Common NAS Performance Issues
NAS performance can be influenced by a variety of factors. Here are some of the most common factors that can impact the performance of a NAS device.
Hardware Limitations:
Insufficient RAM: Especially in tasks like media streaming or handling large files, having inadequate memory can slow down operations.
Slow CPU: An underpowered processor can become a bottleneck when multiple users access the NAS at once or during collaboration with team members.
Drive Speed and Type: Hard disk drives (HDDs) are generally slower compared to solid state drives (SSDs), and your NAS can have either type. If your NAS mainly serves as a hub for storing and sharing files, a conventional HDD should meet your requirements. However, for those seeking enhanced speed and performance, SSDs deliver the performance you need.
Outdated Hardware: Older NAS models might not be equipped to handle modern data demands or the latest software.
Software Limitations:
Outdated Firmware/Software: Not updating to the latest firmware or software can lead to performance issues, or to missing out on optimization and security features.
Misconfigured Settings: Incorrect settings can impact performance. This includes improper RAID configuration or network settings.
Background Processes: Certain background tasks, like indexing or backups, can also slow down the system when running.
Network Challenges:
Bandwidth Limitations: A slow network connection, especially on a Wi-Fi network can limit data transfer rates.
Network Traffic: High traffic on the network can cause congestion, reducing the speed at which data can be accessed or transferred.
Disk Health and Configuration:
Disk Failures: A failing disk in the NAS can slow down performance and also poses data loss risk.
Suboptimal RAID Configuration: Some RAID configurations prioritize redundancy more than performance, which can affect the data storage and access speeds.
External Factors:
Simultaneous User Access: If multiple users are accessing, reading, or writing to the NAS simultaneously, it can strain the system, especially if the hardware isn’t optimized to such traffic from multiple users.
Inadequate Power Supply: Fluctuating or inadequate power can cause the NAS to malfunction or reduce its performance.
Operating Temperature: Additionally, if the NAS is in a hot environment, it might overheat and impact the performance of the device.
Practical Solutions for Optimizing NAS Performance
Understanding the common performance issues with NAS devices is the first critical step. However, simply identifying these issues alone isn’t enough. It’s vital to understand practical ways to optimize your existing NAS setup so you can enhance its speed, efficiency, and reliability. Let’s explore how to optimize your NAS.
Performance Enhancement 1: Upgrading Hardware
There are a few different things you can do on a hardware level to enhance NAS performance. First, adding more RAM can significantly improve performance, especially if multiple tasks or users are accessing the NAS simultaneously.
You can also consider switching to SSDs. While they can be more expensive, SSDs offer faster read/write speeds than traditional HDDs, and they store data in flash memory, which means that they retain information even without power.
Finally, you could upgrade the CPU. For NAS devices that support it, a more powerful CPU can better handle multiple simultaneous requests and complex tasks.
Remember to always keep your NAS operating system and software up-to-date to benefit from the latest performance optimizations and security patches. Schedule tasks like indexing, backups or antivirus scans during off-peak hours to ensure they don’t impact user access during high-traffic times. You also need to make sure you’re using the right RAID configuration for your needs. RAID 5 or RAID 6, for example, can offer a good balance between redundancy and performance.
Performance Enhancement 3: Network Enhancements
Consider moving to faster network protocols, like 10Gb ethernet, or ensuring that your router and switches can handle high traffic. Wherever possible, use wired connections instead of Wi-Fi to connect to the NAS for more stable and faster data access and transfer. And, regularly review and adjust network settings for optimal performance. If you can, it also helps to limit simultaneous access. If possible, manage peak loads by setting up access priorities.
Performance Enhancement 4: Regular Maintenance
Use your NAS device’s built-in tools or third-party software to monitor the health of your disks and replace any that show signs of failure. And, keep the physical environment around your NAS device clean, cool, and well ventilated to prevent overheating.
Leveraging the Cloud for NAS Optimization
After taking the necessary steps to optimize your NAS for improved performance and reliability, it’s worth considering leveraging the cloud to further enhance the performance. While NAS offers convenient local storage, it can sometimes fall short when it comes to scalability, accessibility from different locations, and seamless collaboration. Here’s where cloud storage comes into play.
At its core, cloud storage is a service model in which data is maintained, managed, and backed up remotely, and made available to users over the internet. Instead of relying solely on local storage solutions such as NAS or a server, you utilize the vast infrastructure of data centers across the globe to store your data not just in one physical location, but across multiple secure and redundant environments.
As an off-site storage solution for NAS, the cloud not only completes your 3-2-1 backup plan, but can also amplify its performance. Let’s take a look at how integrating cloud storage can help optimize your NAS.
Off-Loading and Archiving: One of the most straightforward approaches is to move infrequently accessed or archival data from the NAS to the cloud. This frees up space on the NAS, ensuring it runs smoothly, while optimizing the NAS by only keeping data that’s frequently accessed or essential.
Caching: Some advanced NAS systems can cache frequently accessed data in the cloud. This means that the most commonly used data can be quickly retrieved, enhancing user experience and reducing the load on the NAS device.
Redundancy and Disaster Recovery: Instead of duplicating data on multiple NAS devices for redundancy, which can be costly and still vulnerable to local disasters, the data can be backed up to the cloud. In case of NAS failure or catastrophic event, the data can be quickly restored from the cloud, ensuring minimal downtime.
Remote Access and Collaboration: While NAS devices can offer remote access, integrating them with cloud storage can streamline this process, often offering a more user-friendly interface and better speeds. This is especially useful for collaborative environments where multiple users work together on files and projects.
Scaling Without Hardware Constraints: As your data volume grows, expanding a NAS can involve purchasing additional drives or even new devices. With cloud integration, you can expand your storage capacity without these immediate hardware investments, eliminating or delaying the need for physical upgrades and extending the lifespan of your NAS.
In essence, integrating cloud storage solutions with your NAS can create a comprehensive system that addresses the shortcomings of NAS devices, helping you create a hybrid setup that offers the best of both worlds: the speed and accessibility of local storage, and the flexibility and scalability of the cloud.
Getting the Best From Your NAS
At its core, NAS offers an unparalleled convenience of localized storage. However, it’s not without challenges, especially when performance issues come into play. Addressing these challenges requires a blend of hardware optimization, software updates, and smart data management settings.
But, it doesn’t have to stop at your local network. Cloud storage can be leveraged effectively to optimize your NAS. It doesn’t just act as a safety net by storing your NAS data off-site, it also makes collaboration easier with dispersed teams and further optimizes NAS performance.
Now, it’s time to hear from you. Have you encountered any NAS performance issues? What measures have you taken to optimize your NAS? Share your experiences and insights in the comments below.
When it comes to navigating the treacherous landscape of a household’s digital ecosystem, from smartphones and laptops to smart homes and millions of subscriptions, there often emerges a silent hero—the ever-humble, quietly toiling, underappreciated Family IT Manager. This unsung role, typically filled by a tech-savvy-est member of the family, takes on the responsibility of keeping everyone’s digital lives running smoothly. Maybe you know one of these vaillant souls. Or maybe, just maybe, it’s you.
As the Family IT Manager, having one more arrow in your quiver with which to slay the dreaded data loss dragon is always helpful. And that’s what Backblaze Groups is all about—making it easier for you to keep track of everyone’s data in one place.
Today, we’re sharing some practical tips and tricks for using Groups to better manage your family’s backups.
Groups helps you manage the backups your family creates without having to log in and out of individual accounts. This makes it simple to keep track of everyone in one place. All the backup accounts are linked to the same credit card (they can Venmo you later), and you can even help someone else in your family create a backup or restore files easily with Groups. Need to help a family member with a computer emergency? Log in, access their most recent backup, and restore everything. Is your sibling unsure that you really added Backblaze to their computer? Log in, view their account, and get the screenshots to prove it to them (and everyone else).
By the way, this would be a great time to give the new Restore App, included with Backblaze Computer Backup v9.0, a spin.
One point of clarification: You might see Backblaze Groups referred to as “Business Groups,” but you don’t have to be a business to use Groups. They work equally well for businesses and personal users alike, including Family IT Managers (and, truly, running family IT is kind of like running a business, isn’t it?).
Why Use Groups?
You can already manage multiple computers on a single Backblaze account. So why use Groups instead? Well, with Groups, each user has individual access to, and control of, their account. You—as Group administrator—manage billing and, as needed, data recovery. This is a more secure and safer method than sharing the same account credentials among several computers used by different people.
Have multiple households or groupings of folks in your life that you need to manage? You can have as many Groups as you like to help you keep track of everyone and everything, and each of those Groups can have separate billing.
What Do I Need to Know About Setting Up Backblaze Groups for My Family?
The Groups feature streamlines the management of the accounts you need to monitor. As the Group administrator, you have total control over who’s included as part of your Group. You can send out email invitations, or alternatively, you can use a unique Group invitation link that allows anyone you share it with to easily join.
Here’s the visual of where you’d find everything in your account.
Being in a Group is entirely voluntary. Any member of a Group can leave any time they want, and Group administrators can also remove individuals from a Group at any time.
If you dissolve your Group for some reason or if someone chooses to leave, the removed person can decide whether they want to keep using Backblaze by establishing their own payment method. Perfect for when it’s time to wean the kiddos off of your shared accounts—whether they like it or not.
One last note: while you can set up and administer more than one Group with separate billing, you can only be a member in one Group.
Once you create a Group, you can invite members to join it. Copy the Group invite link Backblaze generates automatically for you. Give it to friends and family via email, chat, or any other means you’d like.
We promise to send the emails. You may have to remind them to check their email.
When the person you’ve invited clicks on the link, they will be prompted to either create a Backblaze account (if they don’t have one) or log in to their existing account. After completing this step, they will be prompted to download Backblaze. If they are already using Backblaze, there is no need for a reinstallation; they will seamlessly become a part of your Group.
Once an existing user successfully joins your Group, they’ll be under your billing account. Their existing credit card will automatically receive a prorated refund for the remaining portion of their previous Backblaze license. There is no need to worry about re-uploading data—their backup remains securely stored in Backblaze.
Newcomers to Backblaze can download and install the client to initiate their initial backup process. As the Group administrator, you will have the capability to monitor their backup progress. Remember that the first backup of data may take some time, but after that, everything will run smoothly in the background.
Go Forth and Conquer, Mighty IT Manager
We understand that being the go-to “tech person” for your family and friends can be challenging. We hope that Groups simplifies the process, making it easier for you to help keep your family’s data safe.
This year, we’re celebrating 10 years of Drive Stats. Coincidentally, we also made some upgrades to how we run our Drive Stats reports. We reported on how an attempt to migrate triggered a weeks-long recalculation of the dataset, leading us to map the architecture of the Drive Stats data.
This follow-up article focuses on the improvements we made after we fixed the existing bug (because hey, we were already in there), and then presents some of our ideas for future improvements. Remember that those are just ideas so far—they may not be live in a month (or ever?), but consider them good food for thought, and know that we’re paying attention so that we can pass this info along to the right people.
Now, onto the fun stuff.
Quick Refresh: Drive Stats Data Architecture
The podstats generator runs on every Storage Pod, what we call any host that holds customer data, every few minutes. It’s a C++ program that collects SMART stats and a few other attributes, then converts them into an .xml file (“podstats”). Those are then pushed to a central host in each datacenter and bundled. Once the data leaves these central hosts, it has entered the domain of what we will call Drive Stats.
Now let’s go into a little more detail: when you’re gathering stats about drives, you’re running a set of modules with dependencies to other modules, forming a data-dependency tree. Each time a module “runs”, it takes information, modifies it, and writes it to a disk. As you run each module, the data will be transformed sequentially. And, once a quarter, we run a special module that collects all the attributes for our Drive Stats reports, collecting data all the way down the tree.
Here’s a truncated diagram of the whole system, to give you an idea of what the logic looks like:
An abbreviated logic map of Drive Stats modules.
As you move down through the module layers, the logic gets more and more specialized. When you run a module, the first thing the module does is check in with the previous module to make sure the data exists and is current. It caches the data to disk at every step, and fills out the logic tree step by step. So for example, drive_stats, being a “per-day” module, will write out a file such as /data/drive_stats/2023-01-01.json.gz when it finishes processing. This lets future modules read that file to avoid repeating work.
This work deduplication process saves us a lot of time overall—but it also turned out to be the root cause of our weeks-long process when we were migrating Drive Stats to our new host. We fixed that by implementing versions to each module.
While You’re There… Why Not Upgrade?
Once the dust from the bug fix had settled, we moved forward to try to modernize Drive Stats in general. Our daily report still ran quite slowly, on the order of several hours, and there was some low-hanging fruit to chase.
Waiting On You, failures_with_stats
First things first, we saved a log of a run of our daily reports in Jenkins. Then we wrote an analyzer to see which modules were taking a lot of time. failures_with_stats was our biggest offender, running for about two hours, while every other module took about 15 minutes.
Not quite two hours.
Upon investigation, the time cost had to do with how the date_range module works. This takes us back to caching: our module checks if the file has been written already, and if it has, it uses the cached file. However, a date range is written to a single file. That is, Drive Stats will recognize “Monday to Wednesday” as distinct from “Monday to Thursday” and re-calculate the entire range. This is a problem for a workload that is essentially doing work for all of time, every day.
On top of this, the raw Drive Stats data, which is a dependency for failures_with_stats, would be gzipped onto a disk. When each new query triggered a request to recalculate all-time data, each dependency would pick up the podstats file from disk, decompress it, read it into memory, and do that for every day of all time. We were picking up and processing our biggest files every day, and time continued to make that cost larger.
Our solution was what I called the “Date Range Accumulator.” It works as follows:
If we have a date range like “all of time as of yesterday” (or any partial range with the same start), consider it as a starting point.
Make sure that the version numbers don’t consider our starting point to be too old.
Do the processing of today’s data on top of our starting point to create “all of time as of today.”
To do this, we read the directory of the date range accumulator, find the “latest” valid one, and use that to determine the delta (change) to our current date. Basically, the module says: “The last time I ran this was on data from the beginning of time to Thursday. It’s now Friday. I need to run the process for Friday, and then add that to the compiled all-time.” And, before it does that, it double checks the version number to avoid errors. (As we noted in our previous article, if it doesn’t see the correct version number, instead of inefficiently running all data, it just tells you there is a version number discrepancy.)
The code is also a bit finicky—there are lots of snags when it comes to things like defining exceptions, such as if we took a drive out of the fleet, but it wasn’t a true failure. The module also needed to be processable day by day to be usable with this technique.
Still, even with all the tweaks, it’s massively better from a runtime perspective for eligible candidates. Here’s our new failures_with_stats runtime:
Ahh, sweet victory.
Note that in this example, we’re running that 60-day report. The daily report is quite a bit quicker. But, at least the 60-day report is a fixed amount of time (as compared with the all-time dataset, which is continually growing).
Code Upgrade to Python 3
Next, we converted our code to Python 3. (Shout out to our intern, Anath, who did amazing work on this part of the project!) We didn’t make this improvement just to make it; no, we did this because I wanted faster JSON processors, and a lot of the more advanced ones did not work with Python 2. When we looked at the time each module took to process, most of that was spent serializing and deserializing JSON.
What Is JSON Parsing?
JSON is an open standard file format that uses human readable text to store and transmit data objects. Many modern programming languages include code to generate and parse JSON-format data. Here’s how you might describe a person named John, aged 30, from New York using JSON:
You can express those attributes into a single line of code and define them as a native object:
x = { 'name':'John', 'age':30, 'city':'New York'}
“Parsing” is the process by which you take the JSON data and make it into an object that you can plug into another programming language. You’d write your script (program) in Python, it would parse (interpret) the JSON data, and then give you an answer. This is what that would look like:
import json

# some JSON:
x = '''
{
	"firstName": "John",
	"age": 30,
	"State": "New York"
}
'''

# parse x:
y = json.loads(x)

# the result is a Python object:
print(y["name"])
If you run this script, you’ll get the output “John.” If you change print(y["name"]) to print(y["age"]), you’ll get the output “30.” Check out this website if you want to interact with the code for yourself. In practice, the JSON would be read from a database, or a web API, or a file on disk rather than defined as a “string” (or text) in the Python code. If you are converting a lot of this JSON, small improvements in efficiency can make a big difference in how a program performs.
And Implementing UltraJSON
Upgrading to Python 3 meant we could use UltraJSON. This was approximately 50% faster than the built-in Python JSON library we used previously.
We also looked at the XML parsing for the podstats files, since XML parsing is often a slow process. In this case, we actually found our existing tool is pretty fast (and since we wrote it 10 years ago, that’s pretty cool). Off-the-shelf XML parsers take quite a bit longer because they care about a lot of things we don’t have to: our tool is customized for our Drive Stats needs. It’s a well known adage that you should not parse XML with regular expressions, but if your files are, well, very regular, it can save a lot of time.
What Does the Future Hold?
Now that we’re working with a significantly faster processing time for our Drive Stats dataset, we’ve got some ideas about upgrades in the future. Some of these are easier to achieve than others. Here’s a sneak peek of some potential additions and changes in the future.
Data on Data
In keeping with our data-nerd ways, I got curious about how much the Drive Stats dataset is growing and if the trend is linear. We made this graph, which shows the baseline rolling average, and has a trend line that attempts to predict linearly.
I envision this graph living somewhere on the Drive Stats page and being fully interactive. It’s just one graph, but this and similar tools available on our website would be 1) fun and 2) lead to some interesting insights for those who don’t dig in line by line.
What About Changing the Data Module?
The way our current module system works, everything gets processed in a tree approach, and they’re flat files. If we used something like SQLite or Parquet, we’d be able to process data in a more depth-first way, and that would mean that we could open a file for one module or data range, process everything, and not have to read the file again.
And, since one of the first things that our Drive Stats expert, Andy Klein, does with our .xml data is to convert it to SQLite, outputting it in a queryable form would save a lot of time.
We could also explore keeping the data as a less-smart filetype, but using something more compact than JSON, such as MessagePack.
Can We Improve Failure Tracking and Attribution?
One of the odd things about our Drive Stats datasets is that they don’t always and automatically agree with our internal data lake. Our Drive Stats outputs have some wonkiness that’s hard to replicate, and it’s mostly because of exceptions we build into the dataset. These exceptions aren’t when a drive fails, but rather when we’ve removed it from the fleet for some other reason, like if we were testing a drive or something along those lines. (You can see specific callouts in Drive Stats reports, if you’re interested.) It’s also where a lot of Andy’s manual work on Drive Stats data comes in each month: he’s often comparing the module’s output with data in our datacenter ticket tracker.
These tickets come from the awesome data techs working in our data centers. Each time a drive fails and they have to replace it, our techs add a reason for why it was removed from the fleet. While not all drive replacements are “failures”, adding a root cause to our Drive Stats dataset would give us more confidence in our failure reporting (and would save Andy comparing the two lists).
The Result: Faster Drive Stats and Future Fun
These two improvements (the date range accumulator and upgrading to Python 3) resulted in hours, and maybe even days, of work saved. Even from a troubleshooting point of view, we often wouldn’t know if the process was stuck, or if this was the normal amount of time the module should take to run. Now, if it takes more than about 15 minutes to run a report, you’re sure there’s a problem.
While the Drive Stats dataset can’t really be called “big data”, it provides a good, concrete example of scaling with your data. We’ve been collecting Drive Stats for just over 10 years now, and even though most of the code written way back when is inherently sound, small improvements that seem marginal become amplified as datasets grow.
Now that we’ve got better documentation of how everything works, it’s going to be easier to keep Drive Stats up-to-date with the best tools and run with future improvements. Let us know in the comments what you’d be interested in seeing.
Some real numbers about the cost of AI components.
The AI tech stack and some of the industry solutions that have been built to serve it.
And, uncertainty.
Defining AI: Complexity and Cost Implications
While ChatGPT, DALL-E, and the like may be the most buzz-worthy of recent advancements, AI has already been a part of our daily lives for several years now. In addition to generative AI models, examples include virtual assistants like Siri and Google Home, fraud detection algorithms in banks, facial recognition software, URL threat analysis services, and so on.
That brings us to the first challenge when it comes to understanding the cost of AI: The type of AI you’re training—and how complex a problem you want it to solve—has a huge impact on the computing resources needed and the cost, both in the training and in the implementation phases. AI tasks are hungry in all ways: they need a lot of processing power, storage capacity, and specialized hardware. As you scale up or down in the complexity of the task you’re doing, there’s a huge range in the types of tools you need and their costs.
To understand the cost of AI, several other factors come into play as well, including:
Latency requirements: How fast does the AI need to make decisions? (e.g. that split second before a self-driving car slams on the brakes.)
Scope: Is the AI solving broad-based or limited questions? (e.g. the best way to organize this library vs. how many times is the word “cat” in this article.)
Actual human labor: How much oversight does it need? (e.g. does a human identify the cat in cat photos, or does the AI algorithm identify them?)
Adding data: When, how, and what quantity new data will need to be ingested to update information over time?
This is by no means an exhaustive list, but it gives you an idea of the considerations that can affect the kind of AI you’re building and, thus, what it might cost.
The Big Three AI Cost Drivers: Hardware, Storage, and Processing Power
In simple terms, you can break down the cost of running an AI to a few main components: hardware, storage, and processing power. That’s a little bit simplistic, and you’ll see some of these lines blur and expand as we get into the details of each category. But, for our purposes today, this is a good place to start to understand how much it costs to ask a bot to create a squirrel holding a cool guitar.
Still not quite there on the guitar. Or the squirrel. How much could this really cost?
First Things First: Hardware Costs
Running an AI takes specialized processors that can handle complex processing queries. We’re early in the game when it comes to picking a “winner” for specialized processors, but these days, the most common processor is a graphical processing unit (GPU), with Nvidia’s hardware and platform as an industry favorite and front-runner.
Google offers folks the ability to rent their TPUs through the cloud starting at $1.20 per chip hour for on-demand service (less if you commit to a contract). Meanwhile, Intel released a sub-$100 USB stick with a full NPU that can plug into your personal laptop, and folks have created their own models at home with the help of open sourced developer toolkits. Here’s a guide to using them if you want to get in the game yourself.
Clearly, the spectrum for chips is vast—from under $100 to millions—and the landscape for chip producers is changing often, as is the strategy for monetizing those chips—which leads us to our next section.
Using Third Parties: Specialized Problems = Specialized Service Providers
Building AI is a challenge with so many moving parts that, in a business use case, you eventually confront the question of whether it’s more efficient to outsource it. It’s true of storage, and it’s definitely true of AI processing. You can already see one way Google answered that question above: create a network populated by their TPUs, then sell access.
Other companies specialize in broader or narrower parts of the AI creation and processing chain. Just to name a few, diverse companies: there’s Hugging Face, Inflection AI, CoreWeave, and Vultr. Those companies have a wide array of product offerings and resources from open source communities like Hugging Face that provide a menu of models, datasets, no-code tools, and (frankly) rad developer experiments to bare metal servers like Vultr that enhance your compute resources. How resources are offered also exist on a spectrum, including proprietary company resources (i.e. Nvidia’s platform), open source communities (looking at you, Hugging Face), or a mix of the two.
This means that, whichever piece of the AI tech stack you’re considering, you have a high degree of flexibility when you’re deciding where and how much you want to customize and where and how to implement an out-of-the box solution.
Ballparking an estimate of what any of that costs would be so dependent on the particular model you want to build and the third-party solutions you choose that it doesn’t make sense to do so here. But, it suffices to say that there’s a pretty narrow field of folks who have the infrastructure capacity, the datasets, and the business need to create their own network. Usually it comes back to any combination of the following: whether you have existing infrastructure to leverage or are building from scratch, if you’re going to sell the solution to others, what control over research or dataset you have or want, how important privacy is and how you’re incorporating it into your products, how fast you need the model to make decisions, and so on.
Welcome to the Spotlight, Storage
And, hey, with all that, let’s not forget storage. At the most basic level of consideration, AI uses a ton of data. How much? Going knowledge says at least an order of magnitude more examples than the problem presented to train an AI model. That means you want 10 times more examples than parameters.
Parameters and Hyperparameters
The easiest way to think of parameters is to think of them as factors that control how an AI makes a decision. More parameters = more accuracy. And, just like our other AI terms, the term can be somewhat inconsistently applied. Here’s what ChatGPT has to say for itself:
That 10x number is just the amount of data you store for the initial training model—clearly the thing learns and grows, because we’re talking about AI.
Preserving both your initial training algorithm and your datasets can be incredibly useful, too. As we talked about before, the more complex an AI, the higher the likelihood that your model will surprise you. And, as many folks have pointed out, deciding whether to leverage an already-trained model or to build your own doesn’t have to be an either/or—oftentimes the best option is to fine-tune an existing model to your narrower purpose. In both cases, having your original training model stored can help you roll back and identify the changes over time.
The size of the dataset absolutely affects costs and processing times. The best example is that ChatGPT, everyone’s favorite model, has been rocking GPT-3 (or 3.5) instead of GPT-4 on the general public release because GPT-4, which works from a much larger, updated dataset than GPT-3, is too expensive to release to the wider public. It also returns results much more slowly than GPT-3.5, which means that our current love of instantaneous search results and image generation would need an adjustment.
And all of that is true because GPT-4 was updated with more information (by volume), more up-to-date information, and the model was given more parameters to take into account for responses. So, it has to both access more data per query and use more complex reasoning to make decisions. That said, it also reportedly has much better results.
Storage and Cost
What are the real numbers to store, say, a primary copy of an AI dataset? Well, it’s hard to estimate, but we can ballpark that, if you’re training a large AI model, you’re going to have at a minimum tens of gigabytes of data and, at a maximum, petabytes. OpenAI considers the size of its training database proprietary information, and we’ve found sources that cite that number as anywhere from 17GB to 570GB to 45TB of text data.
That’s not actually a ton of data, and, even taking the highest number, it would only cost $225 per month to store that data in Backblaze B2 (45TB * $5/TB/mo), for argument’s sake. But let’s say you’re training an AI on video to, say, make a robot vacuum that can navigate your room or recognize and identify human movement. Your training dataset could easily reach into petabyte scale (for reference, one petabyte would cost $5,000 per month in Backblaze B2). Some research shows that dataset size is trending up over time, though other folks point out that bigger is not always better.
On the other hand, if you’re the guy with the Intel Neural Compute stick we mentioned above and a Raspberry Pi, you’re talking the cost of the ~$100 AI processor, ~$50 for the Raspberry Pi, and any incidentals. You can choose to add external hard drives, network attached storage (NAS) devices, or even servers as you scale up.
Storage and Speed
Keep in mind that, in the above example, we’re only considering the cost of storing the primary dataset, and that’s not very accurate when thinking about how you’d be using your dataset. You’d also have to consider temporary storage for when you’re actually training the AI as your primary dataset is transformed by your AI algorithm, and nearly always you’re splitting your primary dataset into discrete parts and feeding those to your AI algorithm in stages—so each of those subsets would also be stored separately. And, in addition to needing a lot of storage, where you physically locate that storage makes a huge difference to how quickly tasks can be accomplished. In many cases, the difference is a matter of seconds, but there are some tasks that just can’t handle that delay—think of tasks like self-driving cars.
For huge data ingest periods such as training, you’re often talking about a compute process that’s assisted by powerful, and often specialized, supercomputers, with repeated passes over the same dataset. Having your data physically close to those supercomputers saves you huge amounts of time, which is pretty incredible when you consider that it breaks down to as little as milliseconds per task.
One way this problem is being solved is via caching, or creating temporary storage on the same chips (or motherboards) as the processor completing the task. Another solution is to keep the whole processing and storage cluster on-premises (at least while training), as you can see in the Microsoft-OpenAI setup or as you’ll often see in universities. And, unsurprisingly, you’ll also see edge computing solutions which endeavor to locate data physically close to the end user.
While there can be benefits to on-premises or co-located storage, having a way to quickly add more storage (and release it if no longer needed), means cloud storage is a powerful tool for a holistic AI storage architecture—and can help control costs.
And, as always, effective backup strategies require at least one off-site storage copy, and the easiest way to achieve that is via cloud storage. So, any way you slice it, you’re likely going to have cloud storage touch some part of your AI tech stack.
What Hardware, Processing, and Storage Have in Common: You Have to Power Them
Here’s the short version: any time you add complex compute + large amounts of data, you’re talking about a ton of money and a ton of power to keep everything running.
Fortunately for us, other folks have done the work of figuring out how much this all costs. This excellent article from SemiAnalysis goes deep on the total cost of powering searches and running generative AI models. The Washington Post cites Dylan Patel (also of SemiAnalysis) as estimating that a single chat with ChatGPT could cost up to 1,000 times as much as a simple Google search. Those costs include everything we’ve talked about above—the capital expenditures, data storage, and processing.
Consider this: Google spent several years putting off publicizing a frank accounting of their power usage. When they released numbers in 2011, they said that they use enough electricity to power 200,000 homes. And that was in 2011. There are widely varying claims for how much a single search costs, but even the most conservative say .03 Wh of energy. There are approximately 8.5 billion Google searches per day. (That’s just an incremental cost by the way—as in, how much does a single search cost in extra resources on top of how much the system that powers it costs.)
Power is a huge cost in operating data centers, even when you’re only talking about pure storage. One of the biggest single expenses that affects power usage is cooling systems. With high-compute workloads, and particularly with GPUs, the amount of work the processor is doing generates a ton more heat—which means more money in cooling costs, and more power consumed.
So, to Sum Up
When we’re talking about how much an AI costs, it’s not just about any single line item cost. If you decide to build and run your own models on-premises, you’re talking about huge capital expenditure and ongoing costs in data centers with high compute loads. If you want to build and train a model on your own USB stick and personal computer, that’s a different set of cost concerns.
And, if you’re talking about querying a generative AI from the comfort of your own computer, you’re still using a comparatively high amount of power somewhere down the line. We may spread that power cost across our national and international infrastructures, but it’s important to remember that it’s coming from somewhere—and that the bill comes due, somewhere along the way.
Welcome to the 2023 Mid-Year SSD Edition of the Backblaze Drive Stats review. This report is based on data from the solid state drives (SSDs) we use as storage server boot drives on our Backblaze Cloud Storage platform. In this environment, the drives do much more than boot the storage servers. They also store log files and temporary files produced by the storage server. Each day a boot drive will read, write, and delete files depending on the activity of the storage server itself.
We will review the quarterly and lifetime failure rates for these drives, and along the way we’ll offer observations and insights to the data presented. In addition, we’ll take a first look at the average age at which our SSDs fail, and examine how well SSD failure rates fit the ubiquitous bathtub curve.
Mid-Year SSD Results by Quarter
As of June 30, 2023, there were 3,144 SSDs in our storage servers. This compares to 2,558 SSDs we reported in our 2022 SSD annual report. We’ll start by presenting and discussing the quarterly data from each of the last two quarters (Q1 2022 and Q2 2023).
Notes and Observations
Data is by quarter: The data used in each table is specific to that quarter. That is, the number of drive failures and drive days are inclusive of the specified quarter, Q1 or Q2. The drive counts are as of the last day of each quarter.
Drives added: Since our last SSD report, ending in Q4 2022, we added 238 SSD drives to our collection. Of that total, the Crucial (model: CT250MX500SSD1) led the way with 110 new drives added, followed by 62 new WDC drives (model: WD Blue SA510 2.5) and 44 Seagate drives (model: ZA250NM1000).
Really high annualized failure rates (AFR): Some of the failure rates, that is AFR, seem crazy high. How could the Seagate model SSDSCKKB240GZR have an annualized failure rate over 800%? In that case, in Q1, we started with two drives and one failed shortly after being installed. Hence, the high AFR. In Q2, the remaining drive did not fail and the AFR was 0%. Which AFR is useful? In this case neither, we just don’t have enough data to get decent results. For any given drive model, we like to see at least 100 drives and 10,000 drive days in a given quarter as a minimum before we begin to consider the calculated AFR to be “reasonable.” We include all of the drive models for completeness, so keep an eye on drive count and drive days before you look at the AFR with a critical eye.
Quarterly Annualized Failures Rates Over Time
The data in any given quarter can be volatile with factors like drive age and the randomness of failures factoring in to skew the AFR up or down. For Q1, the AFR was 0.96% and, for Q2, the AFR was 1.05%. The chart below shows how these quarterly failure rates relate to previous quarters over the last three years.
As you can see, the AFR fluctuates between 0.36% and 1.72%, so what’s the value of quarterly rates? Well, they are useful as the proverbial canary in a coal mine. For example, the AFR in Q1 2021 (0.58%) jumped 1.51% in Q2 2021, then to 1.72% in Q3 2021. A subsequent investigation showed one drive model was the primary cause of the rise and that model was removed from service.
It happens from time to time that a given drive model is not compatible with our environment, and we will moderate or even remove that drive’s effect on the system as a whole. While not as critical as data drives in managing our system’s durability, we still need to keep boot drives in operation to collect the drive/server/vault data they capture each day.
How Backblaze Uses the Data Internally
As you’ve seen in our SSD and HDD Drive Stats reports, we produce quarterly, annual, and lifetime charts and tables based on the data we collect. What you don’t see is that every day we produce similar charts and tables for internal consumption. While typically we produce one chart for each drive model, in the example below we’ve combined several SSD models into one chart.
The “Recent” period we use internally is 60 days. This differs from our public facing reports which are quarterly. In either case, charts like the one above allow us to quickly see trends requiring further investigation. For example, in our chart above, the recent results of the Micron SSDs indicate a deeper dive into the data behind the charts might be necessary.
By collecting, storing, and constantly analyzing the Drive Stats data we can be proactive in maintaining our durability and availability goals. Without our Drive Stats data, we would be inclined to over-provision our systems as we would be blind to the randomness of drive failures which would directly impact those goals.
A First Look at More SSD Stats
Over the years in our quarterly Hard Drive Stats reports, we’ve examined additional metrics beyond quarterly and lifetime failure rates. Many of these metrics can be applied to SSDs as well. Below we’ll take a first look at two of these: the average age of failure for SSDs and how well SSD failures correspond to the bathtub curve. In both cases, the datasets are small, but are a good starting point as the number of SSDs we monitor continues to increase.
The Average Age of Failure for SSDs
Previously, we calculated the average age at which a hard drive in our system fails. In our initial calculations that turned out to be about two years and seven months. That was a good baseline, but further analysis was required as many of the drive models used in the calculations were still in service and hence some number of them could fail, potentially affecting the average.
We are going to apply the same calculations to our collection of failed SSDs and establish a baseline we can work from going forward. Our first step was to determine the SMART_9_RAW value (power-on-hours or POH) for the 63 failed SSD drives we have to date. That’s not a great dataset size, but it gave us a starting point. Once we collected that information, we computed that the average age of failure for our collection of failed SSDs is 14 months. Given that the average age of the entire fleet of our SSDs is just 25 months, what should we expect to happen as the average age of the SSDs still in operation increases? The table below looks at three drive models which have a reasonable amount of data.
Good Drives
Failed Drives
MFG
Model
Count
Avg Age
Count
Avg Age
Crucial
CT250MX500SSD1
598
11 months
9
7 months
Seagate
ZA250CM10003
1,114
28 months
14
11 months
Seagate
ZA250CM10002
547
40 months
17
25 months
As we can see in the table, the average age of the failed drives increases as the average age of drives in operation (good drives) increases. In other words, it is reasonable to expect that the average age of SSD failures will increase as the entire fleet gets older.
Is There a Bathtub Curve for SSD Failures?
Previously we’ve graphed our hard drive failures over time to determine their fit to the classic bathtub curve used in reliability engineering. Below, we used our SSD data to determine how well our SSD failures fit the bathtub curve.
While the actual curve (blue line) produced by the SSD failures over each quarter is a bit “lumpy”, the trend line (second order polynomial) does have a definite bathtub curve look to it. The trend line is about a 70% match to the data, so we can’t be too confident of the curve at this point, but for the limited amount of data we have, it is surprising to see how the occurrences of SSD failures are on a path to conform to the tried-and-true bathtub curve.
SSD Lifetime Annualized Failure Rates
As of June 30, 2023, there were 3,144 SSDs in our storage servers. The table below is based on the lifetime data for the drive models which were active as of the end of Q2 2023.
Notes and Observations
Lifetime AFR: The lifetime data is cumulative from Q4 2018 through Q2 2023. For this period, the lifetime AFR for all of our SSDs was 0.90%. That was up slightly from 0.89% at the end of Q4 2022, but down from a year ago, Q2 2022, at 1.08%.
High failure rates?: As we noted with the quarterly stats, we like to have at least 100 drives and over 10,000 drive days to give us some level of confidence in the AFR numbers. If we apply that metric to our lifetime data, we get the following table.
Applying our modest criteria to the list eliminated those drive models with crazy high failure rates. This is not a statistics trick; we just removed those models which did not have enough data to make the calculated AFR reliable. It is possible the drive models we removed will continue to have high failure rates. It is also just as likely their failure rates will fall into a more normal range. If this technique seems a bit blunt to you, then confidence intervals may be what you are looking for.
Confidence intervals: In general, the more data you have and the more consistent that data is, the more confident you are in the predictions based on that data. We calculate confidence intervals at 95% certainty.
For SSDs, we like to see a confidence interval of 1.0% or less between the low and the high values before we are comfortable with the calculated AFR. If we apply this metric to our lifetime SSD data we get the following table.
This doesn’t mean the failure rates for the drive models with a confidence interval greater than 1.0% are wrong; it just means we’d like to get more data to be sure.
Regardless of the technique you use, both are meant to help clarify the data presented in the tables throughout this report.
The SSD Stats Data
The data collected and analyzed for this review is available on our Drive Stats Data page. You’ll find SSD and HDD data in the same files and you’ll have to use the model number to locate the drives you want, as there is no field to designate a drive as SSD or HDD. You can download and use this data for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, and 3) you do not sell this data to anyone—it is free.
Good luck and let us know if you find anything interesting.
Rclone v1.64.0, released last week, includes a new implementation of multithreaded data transfers, promising much faster data transfer of large files between cloud storage services.
Does it deliver? Should you upgrade? Read on to find out!
Multithreading to Boost File Transfer Performance
Something of a Swiss Army Knife for cloud storage, rclone can copy files, synchronize directories, and even mount remote storage as a local filesystem. Previous versions of rclone were able to take advantage of multithreading to accelerate the transfer of “large” files (by default at least 256MB), but the benefits were limited.
When transferring files from a storage system to Backblaze B2, rclone would read chunks of the file into memory in a single reader thread, starting a set of multiple writer threads to simultaneously write those chunks to Backblaze B2. When the source storage was a local disk (the common case) as opposed to remote storage such as Backblaze B2, this worked really well—the operation of moving files from local disk to Backblaze B2 was quite fast. However, when the source was another remote storage—say, transferring from Amazon S3 to Backblaze B2, or even Backblaze B2 to Backblaze B2—data chunks were read into memory by that single reader thread at about the same rate as they could be written to the destination, meaning that all but one of the writer threads were idle.
What’s the Big Deal About Rclone v1.64.0?
Rclone v1.64.0 completely refactors multithreaded transfers. Now rclone starts a single set of threads, each of which both reads a chunk of data from the source service into memory, and then writes that chunk to the destination service, iterating through a subset of chunks until the transfer is complete. The threads transfer their chunks of data in parallel, and each transfer is independent of the others. This architecture is both simpler and much, much faster.
Show Me the Numbers!
How much faster? I spun up a virtual machine (VM) via our compute partner, Vultr, and downloaded both rclone v1.64.0 and the preceding version, v1.63.1. As a quick test, I used Rclone’s copyto command to copy 1GB and 10GB files from Amazon S3 to Backblaze B2, like this:
Note that I made no attempt to “tune” rclone for my environment by setting the chunk size or number of threads. I was interested in the out of the box performance. I used the --no-check-dest flag so that rclone would overwrite the destination file each time, rather than detecting that the files were the same and skipping the copy.
I ran each copyto operation three times, then calculated the average time. Here are the results; all times are in seconds:
Rclone version
1GB
10GB
1.63.1
52.87
725.04
1.64.0
18.64
240.45
As you can see, the difference is significant! The new rclone transferred both files around three times faster than the previous version.
So, copying individual large files is much faster with the latest version of rclone. How about migrating a whole bucket containing a variety of file sizes from Amazon S3 to Backblaze B2, which is a more typical operation for a new Backblaze customer? I used rclone’s copy command to transfer the contents of an Amazon S3 bucket—2.8GB of data, comprising 35 files ranging in size from 990 bytes to 412MB—to a Backblaze B2 Bucket:
Much to my dismay, this command failed, returning errors related to the files being corrupted in transfer, for example:
2023/09/18 16:00:37 ERROR : tpcds-benchmark/catalog_sales/20221122_161347_00795_djagr_3a042953-d0a2-4b8d-8c4e-6a88df245253: corrupted on transfer: sizes differ 244695498 vs 0
Rclone was reporting that the transferred files in the destination bucket contained zero bytes, and deleting them to avoid the use of corrupt data.
After some investigation, I discovered that the files were actually being transferred successfully, but a bug in rclone 1.64.0 caused the app to incorrectly interpret some successful transfers as corrupted, and thus delete the transferred file from the destination.
I was able to use the --ignore-size flag to workaround the bug by disabling the file size check so I could continue with my testing:
A Word of Caution to Control Your Transaction Fees
Note the use of the --fast-list flag. By default, rclone’s method of reading the contents of cloud storage buckets minimizes memory usage at the expense of making a “list files” call for every subdirectory being processed. Backblaze B2’s list files API, b2_list_file_names, is a class C transaction, priced at $0.004 per 1,000 with 2,500 free per day. This doesn’t sound like a lot of money, but using rclone with large file hierarchies can generate a huge number of transactions. Backblaze B2 customers have either hit their configured caps or incurred significant transaction charges on their account when using rclone without the --fast-list flag.
We recommend you always use --fast-list with rclone if at all possible. You can set an environment variable so you don’t have to include the flag in every command:
export RCLONE_FAST_LIST=1
Again, I performed the copy operation three times, and averaged the results:
Rclone version
2.8GB tree
1.63.1
56.92
1.64.0
42.47
Since the bucket contains both large and small files, we see a lesser, but still significant, improvement in performance with rclone v1.64.0—it’s about 33% faster than the previous version with this set of files.
So, Should I Upgrade to the Latest Rclone?
As outlined above, rclone v1.64.0 contains a bug that can cause copy (and presumably also sync) operations to fail. If you want to upgrade to v1.64.0 now, you’ll have to use the --ignore-size workaround. If you don’t want to use the workaround, it’s probably best to hold off until rclone releases v1.64.1, when the bug fix will likely be deployed—I’ll come back and update this blog entry when I’ve tested it!
A while back, I received a frantic phone call from a long time friend who teaches ninth grade English. Now, don’t get me wrong, this friend, let’s call her Alex, is a tech-savvy person. She has more apps on her smartphone than I knew existed, but she had never used an external hard drive before.
Her school district had given them out to help make remote learning easier on teachers, but she was nervous about using it incorrectly, breaking it, or even just being able to find it on her computer. And she was a little embarrassed because it seemed like something everyone else already knew how to use.
If you’ve ever felt a bit lost when it comes to hard drives, don’t worry—you’re not alone. If you’re one of many folks who’ve asked themselves, “What is this thing?” and “How will it be helpful to me?” and “What if I break it?” then I’m here to walk you through everything I walked Alex through. Lots of folks have the same questions, and we’ll answer them in this guide for setting up and protecting your new hard drive.
A Guide to Setting Up Your First External Hard Drive
Getting Started
While it might seem like a no-brainer, the first step for setting up your hard drive is to plug it into your computer. Small, external, portable hard drives typically have one cord that plugs into your computer so you can transfer data. It also powers the hard drive. Some models may have another cord for added power—if so, you’ll want to plug in both.
Finding Your Hard Drive on Your Computer
On a Mac, locating your connected external drive is straightforward. Open Finder, which you can access by clicking the default Finder icon in your applications Dock, using Command + Space bar to search for Finder, or pressing Shift + Command + C. Once in Finder, your drives should appear either immediately or in the left-hand navigation column under “Locations.” Click on the specific drive you want to access to view its contents.
For Windows computers, the steps may vary depending on your Windows version. In general, you can find your drives in File Explorer by clicking on Computer or This PC in the left-hand navigation bar of a File Explorer window. If you’re unsure how to open File Explorer, look for it in your Start Menu, or try clicking on your desktop and pressing Windows Key + E together. Once you’ve located your drives, simply click on the one you wish to explore to access its contents.
Saving Files to Your External Hard Drive
External hard drives are a breeze to use. Once you’ve plugged them in and found them on your computer, you can simply copy files onto the hard drive by clicking and dragging them into the Finder or File Explorer window. This creates a copy on your hard drive, while leaving the original on your computer or laptop.
External Hard Drive Best Practices
Once you know how to use your external hard drive, there are a number of things you can do to maintain it and keep it organized. Your hard drive will fail eventually (more on that later), but there are things you can do to keep it working as long as possible. And there are things you can do to make sure you can easily find what you’re looking for.
1. Keep Your Drive Clean
Maintaining the cleanliness of your external hard drive involves two essential steps: caring for the hard drive itself and keeping the surrounding computer area tidy. The biggest priority is to ensure that both your hard drive and its immediate environment remain free from dust. A dust-free environment contributes to unimpeded airflow within your device, reducing the risk of overheating. If your hard drive has already been exposed to a dusty environment, compressed air is the most effective cleaning tool to remove it.
To effectively use compressed air, first identify key areas for cleaning. Look for the fan vent, inspect the USB ports, and examine other spots on the external hard drive that may accumulate dust over time. Then, simply blast those areas with the compressed air to remove some of the built up dust. (Bonus: it’s super fun.)
Lastly, it’s crucial to maintain an uncluttered area around your external hard drive to facilitate optimal airflow. Take the time to relocate any objects that might obstruct the airflow, such as books, papers, and other potential obstructions. This simple step can significantly enhance the longevity and performance of your external hard drive.
2. Keep Your Operating System Up to Date
The second best practice has more to do with your computer or laptop than your hard drive, but that’s what your hard drive connects to—so it’s important to keep it working, too.
We have all hit “remind me later” on an update dialog from our computer at some point in our lives, but updating your operating system (OS) will ensure that your computer is secure, that your system can run better, and that hard drives are able to properly connect to your files. Updating your OS can vary depending on what kind of computer you have. The best place to look for how to update your OS is in your system’s preferences.
Depending on the age of your computer, however, you should reach out to your local IT person before updating. Some older computers are not able to run, or run very poorly, on newer systems.
3. Know What’s On Your External Hard Drive
External hard drives are simple: you plug them in, they appear on your computer, and you can simply click and drag your files onto them to copy the files onto the hard drive. If you’re a more advanced user, you may have set up your external hard drive so that there are files that only exist on that device. Either way, it’s important to monitor what’s on your external hard drive and minimize digital clutter, just like you would with your computer or laptop. You can do this by periodically checking your drive to make sure your files are up to date and still needed.
4. Delete Duplicates
When you’re reviewing the contents of your external hard drive, keep in mind the significance of deleting duplicates. There are times when we unintentionally generate multiple copies of a project or document or save several versions of the same file, especially when finalizing edits. Removing redundant duplicates not only contributes to a speedier hard drive performance but also creates room for additional files. You can either manually inspect your files for duplications or use specialized applications designed to detect and delete duplicate files residing on your drive.
Protecting Your Data on an External Hard Drive
3-2-1 Backup
Implementing a 3-2-1 backup strategy means maintaining a minimum of three complete copies of your data. Two of these copies should reside locally but on distinct types of media, such as an external hard drive. The third copy must be stored offsite, away from your primary location. For instance, if you have your files on your computer and an external hard drive (which should be stored separately from your computer when not in use), you should maintain one additional copy stored independently, beyond the confines of your home. This is where the cloud comes in.
There are several cloud-based services that will back up your computer and your attached drives. We’re partial to our own, of course, and, here’s our guide to making sure your external hard drives are backed up. And, with Backblaze’s Forever Version History, you’ll always have a copy of your hard drive data, updated from the most recent time you plugged it in.
Prepare for a Drive Failure
The only truth about computer hardware is that it will fail eventually. We know a little bit about that. Most hard drive manufacturer warranties span only three to five years, and budget-friendly drives often have even shorter lifespans. These time frames don’t factor in variables like physical wear and tear, specific make or model, or storage conditions.
When using an external hard drive, you have to prepare for the day that it fails. Fortunately, there are several methods to monitor your external hard drive’s health, with telltale signs that it’s approaching the end of its service life. These signs may include unusual clicking or screeching sounds, sluggish performance, and frequent errors when attempting to access folders on the drive. You can also manually assess your drives’ status directly from your computer.
How to Find Out if Your Drive Is Failing
For a Windows computer, you’ll use a simple command prompt that will tell your computer where to look and what to check. Just right-click the Start menu on your computer, select Run, and type “cmd” or type “cmd” into the search bar. In the Command Line window that opens, copy and paste wmic diskdrive get status and hit enter. This command will run and it will return “Pred Fail” if your drive is not performing, or “OK” if the drive is performing well.
For a Mac computer, you can monitor the status of your external hard drive by opening Disk Utility. You can find it by going to Applications and then Utilities. Next, you will click on the drive you would like to test to see how it’s performing. Click the View button in the toolbar, then select Show SMART Status. This will display the SMART status of your hard drive as either “Verified” (healthy) or “Failing” (indicating a potential problem). Disk Utility will not detect or repair all problems that a disk may have, but it can give you a general picture.
Note: The process for running these diagnostics may vary slightly depending on your OS and the specific utility you use.
How to Run SMART Diagnostics on Your Hard Drive
Running SMART (Self-Monitoring, Analysis, and Reporting Technology) diagnostics on your hard drive is a smart (see what we did there?) way to assess its health and predict potential issues. SMART diagnostics provide valuable insights into your drive’s performance and can help you detect problems before they lead to data loss. You can use third-party software utilities like CrystalDiskInfo or HDDScan to access more detailed SMART data and view drive health in a user-friendly interface. Download and install one of these tools, then launch it and select your hard drive to view its SMART attributes and health status.
In Conclusion
Starting out with an external hard drive is exactly like starting out with any piece of technology you might own. The more you educate yourself on the ins and outs of taking care of it, the better it will run for you. But if something bad were to happen, you should always have a backup plan (we suggest Backblaze, but you probably already know that) to protect your new piece of equipment.
External Hard Drive FAQs
1. How do I find a hard drive on my computer?
On a Mac, open Finder. Once in Finder, your drives should appear either immediately or in the left-hand navigation column under “Locations.” For Windows computers, the steps may vary depending on your Windows version. In general, you can find your drives in File Explorer by clicking on Computer or This PC in the left-hand navigation bar of a File Explorer window.
2. How do I save files to a hard drive?
Once you’ve plugged in your hard drive and found it on your computer, you can simply copy files onto the hard drive by clicking and dragging them into the Finder or File Explorer window. This creates a copy on your hard drive, while leaving the original on your computer or laptop.
3. How do I keep my hard drive maintained?
Keeping your drive clean and dust-free is the best way to maintain it. This involves two essential steps: caring for the hard drive itself and keeping the surrounding computer area tidy. The biggest priority is to ensure that both your hard drive and its immediate environment remain free from dust. A dust-free environment contributes to unimpeded airflow within your device, reducing the risk of overheating. If your hard drive has already been exposed to a dusty environment, compressed air is the most effective cleaning tool to remove it.
4. How do I know if my hard drive is failing?
There are several telltale signs that your hard drive is approaching the end of its service life. These signs may include unusual clicking or screeching sounds, sluggish performance, and frequent errors when attempting to access folders on the drive. You can also manually assess your drives’ status directly from your computer.
Get ready. The release of Backblaze Computer Backup 9.0 is rolling out now through the end of September.
Backblaze Computer Backup 9.0 is available today in early access, and restoring your files is about to get a whole lot easier.
What’s New in Backblaze Computer Backup 9.0?
Whether you’re a longtime user or just getting started with Backblaze, version 9.0 provides you with an unparalleled backup and restore solution. With our latest release, you get our most requested feature: a dedicated restore app for both macOS and Windows clients that makes the process of restoring your data even more intuitive, seamless, and streamlined than before. The new version also comes with essential bug fixes and performance improvements to keep your back up experience ahead of the curve for both security and speed.
Backblaze Restore App: macOS and Windows Highlights
Whether you’re using our macOS or Windows clients, you can now recover your important data with even more ease.
The restore app sign in screen.Your library of files in the restore app. What it looks like when you prepare a restore. A handy Restore Log so you can track your progress.Check out some of the things you can expect to see from the restore app.
Here’s a peek into some of the new features we have in store with our new Restore Client App:
Simplified restore initiation process. When you’ve lost important files, the last thing you want is a demanding process sitting between you and restoring your data. With the restore app, you authenticate your Backblaze account and initiate the restore directly from your desktop. Once authenticated, you can browse your file tree and kick off the restore process immediately.
No limits for restore size. There are no limits to restore sizes inside of the restore app. Conserving disk space is important and you shouldn’t have to worry about downloading a .zip and having enough additional space to unzip it as well.
If you’re interested in a comprehensive tutorial on how to use the new restore app, we’re here to guide you. Let us walk you through the process.
We’re excited that our version 9.0 release compliments your already robust methods of accessing your data. To access your backup from anywhere, you can log in to www.backblaze.com to initiate a restore and use our iOS and Android apps to access your files on the go.
Backblaze v9.0 Is Available in Early Access Today: September 13, 2023
We will be taking feedback and slowly auto-updating all users in the coming weeks, but if you can’t wait and want to download the early access release now on your Mac or PC:
Go to: https://www.backblaze.com/status/backup-beta
Select your operating system and download the v9.0 app.
Install the early access release on your computer.
Please note, since this is in early access you might hit some bugs. Please reach out to our Support Team if you have any questions or if you want to give feedback—we always like to know how things are going.
This year, we’re celebrating 10 years of Drive Stats—that’s 10 years of collecting the data and sharing the reports with all of you. While there’s some internal debate about who first suggested publishing the failure rates of drives, we all agree that Drive Stats has had impact well beyond our expectations. As of today, Drive Stats is still one of the only public datasets about drive usage, has been cited 150+ times by Google Scholar, and always sparks lively conversation, whether it’s at a conference, in the comments section, or in one of the quarterly Backblaze Engineering Week presentations.
This article is based on a presentation I gave during Backblaze’s internal Engineering Week, and is the result of a deep dive into managing and improving the architecture of our Drive Stats datasets. So, without further ado, let’s dive down the Drive Stats rabbit hole together.
More to Come
This article is part of a series on the nuts and bolts of Drive Stats. Up next, we’ll highlight some improvements we’ve made to the Drive Stats code, and we’ll link to them here. Stay tuned!
A “Simple” Ask
When I started at Backblaze in 2020, one of the first things I was asked to do was to “clean up Drive Stats.” It had not not been ignored per se, which is to say that things still worked, but it took forever and the teams that had worked on it previously were engaged in other projects. While we were confident that we had good data, running a report took about two and a half hours, plus lots of manual labor put in by Andy Klein to scrub and validate drives in the dataset.
On top of all that, the host on which we stored the data kept running out of space. But, each time we tried to migrate the data, something went wrong. When I started a fresh attempt at moving our dataset between hosts for this project, then ran the report, it ran for weeks (literally).
Trying to diagnose the root cause of the issue was challenging due to the amount of history surrounding the codebase. There was some code documentation, but not a ton of practical knowledge. In short, I had my work cut out for me.
Drive Stats Data Architecture
Let’s start with the origin of the data. The podstats generator runs on every Backblaze Storage Pod, what we call any host that holds customer data, every few minutes. It’s a legacy C++ program that collects SMART stats and a few other attributes, then converts them into an .xml file (“podstats”). Those are then pushed to a central host in each data center and bundled. Once the data leaves these central hosts, it has entered the domain of what we will call Drive Stats. This is a program that knows how to populate various types of data, within arbitrary time bounds based on the underlying podstats .xml files. When we run our daily reports, the lowest level of data are the raw podstats. When we run a “standard” report, it looks for the last 60 days or so of podstats. If you’re missing any part of the data, Drive Stats will download the necessary podstats .xml files.
Now let’s go into a little more detail: when you’re gathering stats about drives, you’re running a set of modules with dependencies to other modules, forming a data dependency tree. Each time a module “runs”, it takes information, modifies it, and writes it to a disk. As you run each module, the data will be transformed sequentially. And, once a quarter, we run a special module that collects all the attributes for our Drive Stats reports, collecting data all the way down the tree.
There’s a registry that catalogs each module, what their dependencies are, and their function signatures. Each module knows how its own data should be aggregated, such as per day, per day per cluster, global, data range, and so on. The “module type” will determine how the data is eventually stored on disk. Here’s a truncated diagram of the whole system, to give you an idea of what the logic looks like:
Let’s take model_hack_table as an example. This is a global module, and it’s a reference table that includes drives that might be exceptions in the data center. (So, any of the reasons Andy might identify in a report for why a drive isn’t included in our data, including testing out a new drive and so on.)
The green drive_stats module takes in the json_podstats file, references the model names of exceptions in model_hack_table, then cross references that information against all the drives that we have, and finally assigns them the serial number, brand name, and model number. At that point, it can do things like get the drive count by data center.
Similarly, pod_drives looks up the host file in our Ansible configuration to find out which Pods we have in which data centers. It then does attributions with a reference table so we know how many drives are in each data center.
As you move down through the module layers, the logic gets more and more specialized. When you run a module, the first thing the module does is check in with the previous module to make sure the data exists and is current. It caches the data to disk at every step, and fills out the logic tree step by step. So for example, drive_stats, being a “per-day” module, will write out a file such as /data/drive_stats/2023-01-01.json.gz when it finishes processing. This lets future modules read that file to avoid repeating work.
This work-deduplication process saves us a lot of time overall—but it also turned out to be the root cause of our weeks-long process when we were migrating Drive Stats to our new host.
Cache Invalidation Is Always Treacherous
We have to go into slightly more detail to understand what was happening. The dependency resolution process is as follows:
Before any module can run, it checks for a dependency.
For any dependency it finds, it checks modification times.
The module has to be at least as old as the dependency, and the dependency has to be at least as old as the target data. If one of those conditions isn’t met, the data is recalculated.
Any modules that get recalculated will trigger a rebuild of the whole branch of the logic tree.
When we moved the Drive Stats data and modules, I kept the modification time of the data (using rsync) because I knew in vague terms that Drive Stats used that for its caching. However, when Ansible copied the source code during the migration, it reset the modification time of the code for all source files. Since the freshly copied source files were younger than the dependencies, that meant the entire dataset was recalculating—and that represents terabytes of raw data dating back to 2013, which took weeks.
Note that Git doesn’t preserve mod times and it doesn’t save source files, which is part of the reason this problem exists. Because the data doesn’t exist at all in Git, there’s no way to clone-while-preserving-date. Any time you do a code update or deploy, you run the risk of this same weeks-long process being triggered. However, this code has been stable for so long, tweaks to it wouldn’t invalidate the underlying base modules, and things more or less worked fine.
To add to the complication, lots of modules weren’t in their own source files. Instead, they were grouped together by function. A drive_days module might also be with a drive_days_by_model, drive_days_by_brand, drive_days_by_size, and so on, meaning that changing any of these modules would invalidate all of the other ones in the same file.
This may sound straightforward, but with all the logical dependencies in the various Drive Stats modules, you’re looking at pretty complex code. This was a poorly understood legacy system, so the invalidation logic was implemented somewhat differently for each module type, and in slightly different terms, making it a very unappealing problem to resolve.
Now to Solve
The good news is that, once identified, the solution was fairly intuitive. We decided to set an explicit version for each module, and save it to disk with the files containing its data. In Linux, there is something called an “extended attribute,” which is a small bit of space the filesystem preserves for metadata about the stored file—perfect for our uses. We now write a JSON object containing all of the dependent versions for each module. Here it is:
To you, it’s just version code pinned in Linux’s extended attributes. To me, it’s beautiful.
Now we will have two sets of versions, one stored on the files written to disk, and another set in the source code itself. So whenever a module is attempting to resolve whether or not it is out of date, it can check the versions on disk and see if they are compatible with the versions in source code. Additionally, since we are using semantic versioning, this means that we can do non-invalidating minor version bumps and still know exactly which code wrote a given file. Nice!
The one downside is that you have to manually specify to preserve extended attributes when using many Unix tools such as rsync (otherwise the version numbers don’t get copied). We chose the new default behavior in the presence of missing extended attributes to be for the module to print a warning and assume it’s current. We had a bunch of warnings the first time the system ran, but we haven’t seen them since. This way if we move the dataset and forget to preserve all the versions, we won’t invalidate the entire dataset by accident—awesome!
Wrapping It All Up
One of the coolest parts about this exploration was finding how many parts of this process still worked, and worked well. The C++ went untouched; the XML parser is still the best tool for the job; the logic of the modules and caching protocols weren’t fundamentally changed and had some excellent benefits for the system at large. We’re lucky at Backblaze that we’ve had many talented people work on our code over the years. Cheers to institutional knowledge.
That’s even more impressive when you think of how Drive Stats started—it was a somewhat off-the-cuff request. “Wouldn’t it be nice if we could monitor what these different drives are doing?” Of course, we knew it would have a positive impact on how we could monitor, use, and buy drives internally, but sharing that information is really what showed us how powerful this information could be for the industry and our community. These days we monitor more than 240,000 drives and have over 21.1 million days of data.
This journey isn’t over, by the way—stay tuned for parts two and three where we talk about improvements we made and some future plans we have for Drive Stats data. As always, feel free to sound off in the comments.
The terms NAS and SAN can be confusing—the technology is similar and, making matters worse, the acronyms are the reverse of each other. NAS stands for network attached storage and SAN stands for storage area network. They were both developed to solve the problem of making stored data available to many users at once. But, they couldn’t be more different in how they achieve that goal.
The TL/DR:
NAS is a single storage device that serves files over ethernet and is relatively inexpensive. NAS devices are easier for a home user or small business to set up.
A SAN is a tightly coupled network of multiple devices that is more expensive and complex to set up and manage. A SAN is better suited for larger businesses and requires administration by IT staff.
Read on and we’ll dissect the nuances of NAS and SANs to help you make informed decisions about which solution best suits your storage needs.
Check Out Our New Technical Documentation Portal
When you’re working on a storage project, you need to be able to find instructions about the tools you’re using quickly. And, it helps if those instructions are easy to use, easy to understand, and easy to share. Our Technical Documentation Portal has been completely overhauled to deliver on-demand content in a user-friendly way so you can find the information you need. Check out the NAS section, including all of our Integration Guides.
Basic Definitions: What Is NAS?
NAS is a device or devices with a large data storage capacity that provides file-based data storage services to other devices on a network. Usually, they also have a client or web portal interface that’s easy to navigate, as well as services like QNAP’s Hybrid Backup Sync or Synology’s Hyper Backup to help manage your files. In other words, NAS is synonymous with user-friendly file sharing.
NAS with eight drive bays for 3.5″ disk drives.
At its core, NAS operates as a standalone device connected to a network, offering shared access to files and folders. NAS volumes appear to the user as network-mounted volumes. The files to be served are typically contained on one or more hard drives in the system, often arranged in RAID arrays. Generally, the more drive bays available within the NAS, the larger and more flexible storage options you have.
Key Characteristics of NAS:
File-Level Access: NAS provides file-level access, ideal for environments where collaborative work and content sharing are paramount.
Simplicity: NAS solutions offer straightforward setups and intuitive interfaces, making them accessible to users with varying levels of technical expertise.
Scalability: While NAS devices can be expanded by adding more drives, there may be limitations in terms of performance and scalability for large-scale enterprise use.
How NAS Works
The NAS device itself is a network node—much like computers and other TCP/IP devices, all of which maintain their own IP address—and the NAS file service uses the ethernet network to send and receive files. This system employs protocols like network file system (NFS) and server message block (SMB), enabling seamless data exchange between multiple users.
The NAS system and clients connect via your local network—all file service occurs via ethernet.
Benefits of NAS
NAS devices are designed to be easy to manage, making them a popular choice for home users, small businesses, and departments seeking straightforward centralized storage. They offer an easy way for multiple users in multiple locations to access data, which is valuable when users are collaborating on projects or need to share information.
For individual home users, if you’re currently using external hard drives or direct attached storage, which can be vulnerable to drive failure, upgrading to a NAS ensures your data is better protected.
For small business or departments, installing NAS is typically driven by the desire to share files locally and remotely, have files available 24/7, achieve data redundancy, have the ability to replace and upgrade hard drives in the system, and most importantly, support integrations with cloud storage that provide a location for necessary automatic data backups.
NAS offers robust access controls and security mechanisms to facilitate collaborative efforts. Moreover, it empowers non-technical individuals to oversee and manage data access through an embedded web server. Its built-in redundancy, often achieved through RAID configurations, ensures solid data resilience. This technology merges multiple drives into a cohesive unit, mimicking a single, expansive volume capable of withstanding the failure of a subset of its constituent drives.
Summary of NAS Benefits:
Relatively inexpensive.
A self-contained solution.
Easy administration.
Remote data availability and 24/7 access.
Wide array of systems and sizes to choose from.
Drive failure-tolerant storage volumes.
Automatic backups to other devices and the cloud.
Limitations of NAS
The weaknesses of NAS primarily revolve around scalability and performance. If more users need access, the server might struggle to keep pace. If you overprovisioned your NAS, you may be able to add storage. But sooner or later you’ll need to upgrade to a more powerful system with a bigger on-board processor, more memory, and faster and larger network connections.
Another drawback ties back to ethernet’s inherent nature. Ethernet divides data into packets, forwarding them to their destination. Yet, depending on network traffic or other issues, potential delays or disorder in packet transmission can hinder file availability until all packets arrive and are put back in order.
Although minor latency (slowness) is not usually noticed by users for small files, in data-intensive domains like video production, where large files are at play, even milliseconds of latency can disrupt operations, particularly video editing workflows.
Basic Definitions: What Is a SAN?
On the other end of the spectrum, SANs are engineered for high-performance and mission-critical applications. They function by connecting multiple storage devices, such as disk arrays or tape libraries, to a dedicated network that is separate from the main local area network (LAN). This isolation ensures that storage traffic doesn’t interfere with regular network traffic, leading to optimized performance and data availability.
Unlike NAS, a SAN operates at the block level, allowing servers to access storage blocks directly. This architecture is optimized for data-intensive tasks like database management and virtualization or video editing, where low latency and consistent high-speed access are essential.
Key Characteristics of SANs:
Block-Level Access: SANs provide direct access to storage blocks, which is advantageous for applications requiring fast, low-latency data retrieval.
Performance: SANs are designed to meet the rigorous demands of enterprise-level applications, ensuring reliable and high-speed data access.
Scalability: SANs offer greater scalability by connecting multiple storage devices, making them suitable for businesses with expanding storage needs.
How Does a SAN Work?
A SAN is built from a combination of servers and storage over a high speed, low latency interconnect that allows direct Fibre Channel (FC) connections from the client to the storage volume to provide the fastest possible performance. The SAN may also require a separate, private ethernet network between the server and clients to keep the file request traffic out of the FC network for even more performance.
By joining together the clients, SAN server, and storage on a FC network, the SAN volumes appear and perform as if it were a directly connected hard drive. Storage traffic over FC avoids the TCP/IP packetization and latency issues, as well as any LAN congestion, ensuring the highest access speed available for media and mission critical stored data.
The SAN management server, storage arrays, and clients all connect via a FC network—all file serving occurs over Fibre Channel.
Benefits of a SAN
Because it’s considerably more complex and expensive than NAS, a SAN is typically used by businesses versus individuals and typically requires administration by an IT staff.
The primary strength of a SAN is that it allows simultaneous shared access to shared storage that becomes faster with the addition of storage controllers. SANs are optimized for data-intensive applications. For example, hundreds of video editors can simultaneously access tens of GB per second of storage simultaneously without straining the network.
SANs can be easily expanded by adding more storage devices, making them suitable for growing storage needs. Storage resources can be efficiently managed and allocated from a central location. SANs also typically include redundancy and fault tolerance mechanisms to ensure data integrity and availability.
Summary of a SAN’s Benefits:
Extremely fast data access with low latency.
Relieves stress on a local area network.
Can be scaled up to the limits of the interconnect.
Operating system level (“native”) access to files.
Often the only solution for demanding applications requiring concurrent shared access.
Limitations of a SAN
The challenge of a SAN can be summed up in its cost and administration requirements—having to dedicate and maintain both a separate ethernet network for metadata file requests and implement a FC network can be a considerable investment. That being said, a SAN is often the only way to provide very fast data access for a large number of users that also can scale to supporting hundreds of users at the same time.
The Main Differences Between NAS and SANs
NAS
SAN
Use case
Often used in homes and small to medium sized businesses.
Often used in professional and enterprise environments.
Cost
Less expensive.
More expensive.
Ease of administration
Easier to manage.
Requires more IT administration.
How data is accessed
Data accessed as if it were a network-attached drive.
Servers access data as if it were a local hard drive.
Speed
Speed is dependent on local TCP/IP ethernet network, typically 1GbE to 10GbE but can be up to 25GbE or even 40GbE connections, and affected by the number of other users accessing the storage at the same time. Generally slower throughput and higher latency due to the nature of ethernet packetization, waiting for the file server, and latency in general.
High speed using Fibre Channel, most commonly available in 16 Gb/s to 32 Gb/s however newer standards can go up to 128 Gb/s. FC can be delivered via high speed ethernet such as 10Gbit or 40Gbit+ networks using protocols such as FCoE and iSCSI.
Network connection
SMB/CIFS, NFS, SFTP, and WebDAV.
Fibre Channel, iSCSI, FCoE.
Scalability
Lower-end not highly scalable; high-end NAS scale to petabytes using clusters or scale-out nodes.
Can add more storage controllers, or expanded storage arrays allowing SAN admins to scale performance, storage, or both.
Networking method
Simply connects to your existing ethernet network.
Simply connects to your existing ethernet network.
Simply connects to your existing ethernet network.
Entry level systems often have a single point of failure, e.g. power supply.
Fault tolerant network and systems with redundant functionality.
Limitations
Subject to general ethernet issues.
Behavior is more predictable in controlled, dedicated environments.
Choosing the Right Solution
When considering a NAS device or a SAN, you might find it helpful to think of it this way: NAS is simple to set up, easy to administer, and great for general purpose applications. Meanwhile, a SAN can be more challenging to set up and administer, but it’s often the only way to make shared storage available for mission critical and high performance applications.
The choice between a NAS device and a SAN hinges on understanding your unique storage requirements and workloads. NAS is an excellent choice for environments prioritizing collaborative sharing and simple management. In contrast, a SAN shines when performance and scalability are top priorities, particularly for businesses dealing with data-heavy applications.
Ultimately, the decision should factor in aspects such as budget, anticipated growth, workload demands, and the expertise of your IT team. Striking the right balance between ease of use, performance, and scalability will help ensure your chosen storage solution aligns seamlessly with your goals.
Are You Using NAS, a SAN, or Both?
If you are using a NAS device or a SAN, we’d love to hear from you about what you’re using and how you’re using them in the comments.
Over the years, the film industry has witnessed constant transformation, from the introduction of sound and color to the digital revolution, 4K, and ultra high definition (UHD). However, a groundbreaking change is now underway, as cloud technology merges with media and entertainment (M&E) workflows, reshaping the way content is created, stored, and shared.
What’s helping to drive this transformation? APIs, or application programming interfaces. For any post facility, indie filmmaker/creator, or media team, understanding what APIs are is the first step in using them to embrace the flexibility, efficiency, and speed of the cloud.
Check Out Our New Technical Documentation Portal
When you’re working on a media project, you need to be able to find instructions about the tools you’re using quickly. And, it helps if those instructions are easy to use, easy to understand, and easy to share. Our Technical Documentation Portal has been completely overhauled to deliver on-demand content in a user-friendly way so you can find the information you need. Check out the API overview page to get you started, then dig into the implementation with the full documentation for our S3 Compatible, Backblaze, and Partner APIs.
From Tape to Digital: A Digital File Revolution
The journey towards the cloud transformation in the M&E industry started with the shift from traditional tape and film to digital formats. This revolutionary transition converted traditional media into digital entities, moving them from workstations to servers, shuttle drives, and shared storage systems. Simultaneously, the proliferation of email and cloud-hosted applications like Gmail, Dropbox, and Office 365 laid the groundwork for a cloud-centric future.
Seamless Collaboration With API-Driven Tools
As time went on, applications began communicating effortlessly with one another, facilitating tasks such as creating calendar invites in Gmail through Zoom and the ability to start Zoom meetings with a command in Slack. These integrations were made possible by APIs that allow applications to interact and share data effectively.
What Are APIs?
APIs are sets of rules and protocols that enable different software applications to communicate and interact with each other, allowing you to access specific functionalities or data from one application to be used in another. APIs facilitate seamless integration between diverse systems, enhancing workflows and promoting interoperability.
Most of us in the film industry are familiar with a GUI, a graphical user interface. It’s how we use applications day in and day out—literally the screens on our programs and computers. But a lot of the tasks we execute via a GUI (like saving files, reading files, and moving files) really are pieces of executable code hidden from us behind a nice button. Think of APIs as another method to execute those same pieces of code, but with code. Code executing code. (Let’s not get into the Skynet complex, and this isn’t AI either.)
Grinding the Gears: A Metaphor for APIs
An easy way to think about APIs is to think of them as gears. Each application has a gear. If we adjust the two gears to talk we simply align them to each other allowing their APIs to establish communication.
Once communications are established, you can start to do some cool stuff. For example, you can migrate a Frame.io archive to a Backblaze B2 Bucket. Or you could use the iconik API to move a file we want to edit with into our Lucidlink filespace, then remove it as soon as we finish our project.
Check out a video about the solution here:
The MovieLabs 2030 Vision and Cloud Integration
As the industry embraced cloud technology, the need for standardization became apparent. Organizations like the Institute of Electrical and Electronics Engineers (IEEE) and the Society of Motion Picture and Television Engineers (SMPTE) worked diligently to establish technical unity across vendors and technologies. However, implementation of these standards lacked persistence. To address this void, the Movie Picture Association (MPA) established MovieLabs, an organization dedicated to researching, testing, and developing new guidelines, processes, and tooling to drive improvements on how content is created. One such set of guidelines is the MovieLabs 2030 Vision.
Core Principles of the MovieLabs 2030 Vision
The MovieLabs 2030 Vision outlines 10 core principles that are aspirational for the film industry to accomplish by 2030. These core principles set the stage with a high importance on cloud technology and interoperability. Interoperability boils down to the ability to use various tools but have them share resources—which is where APIs come in. APIs help make tools interoperable and able to share resources. It’s a key functionality, and it’s how many cloud tools work together today.
MovieLab’s 2030 Vision aspirational principles.
The Future Is Here: Cloud Technology at Its Peak
Cloud technology grants us instant access to digital documents and the ability to carry our entire lives in our pockets. With the right tools, our data is securely synced, backed up, and accessible across devices, from smartphones to laptops and even TVs.
Although cloud technology has revolutionized various industries, the media and entertainment sector lagged behind, relying on cumbersome shuttle drives and expensive file systems for our massive files. The COVID pandemic, however, acted as a catalyst for change, pushing the industry to seriously consider the benefits of cloud integration.
Breaking Down Silos With APIs
In a post-pandemic world, many popular media and entertainment applications are built in the cloud, the same as other software as a service (SaaS) applications like Zoom, Slack, or Outlook. Which is great! But many of these tools are designed to best operate in their own ecosystem, meaning once the files are in their systems, it’s not easy to take them out. This may sound familiar if you are an iPhone user faced with migrating to an Android or vice versa. (But who would do that? )
With each of these applications working in their own ecosystem, the result is their own dedicated storage and usage costs which can vary greatly across tools. So many productions end up with projects and project files locked in various different environments creating storage silos—the opposite of centralized interoperability.
APIs not only foster interoperability in cloud-based business applications, but also empower filmmaking cloud tools like Frame.io, iconik, and Backblaze the ability to send, receive, and delete files (the POST, GET, PUT, and DELETE commands) data from other programs, enabling more dynamic and advanced workflows, such as sending files to colorists or reviewing edits for picture lock.
Customized Workflows and Automation
APIs offer the flexibility to tailor workflows to specific needs, whether within a single company or for vendor-specific processes. The automation possibilities are virtually limitless, facilitating seamless integration between cloud tools and storage solutions.
The Road Ahead for Media and Entertainment
The Movie Labs 2030 Vision offers a glimpse into a future defined by cloud tools and automation. Principally, that cloud technology with open and extensible storage exists and is available today.
So for any post facility, indie filmmaker/creator, or media team still driving around shuttle drives while James Cameron is shooting Avatar in New Zealand and editing it in Santa Monica, the future is here and within reach. You can get started today with all the power and flexibility of the cloud without the Avatar budget.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.




 ︎


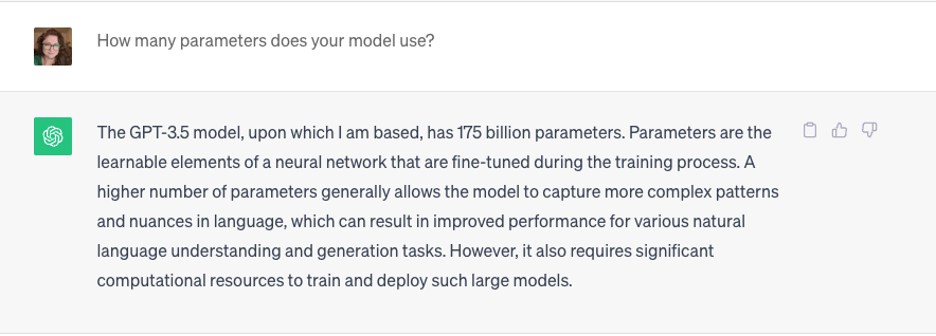




 )

