Welcome to the 26th edition of Cloudflare's DDoS Threat Report. This edition covers the third quarter of 2026 — July, August, and September — and returns the series to its quarterly cadence following the combined H1 2026 volume. The analysis is produced by Cloudforce One, Cloudflare's Threat Intelligence organization, providing a comprehensive analysis of the evolving threat landscape of Distributed Denial of Service (DDoS) attacks based on data from the Cloudflare network.
Key insights
Short-burst, low-bandwidth attacks lasting under 10 minutes and 1 Gbps surged by 208%. Conversely, hyper-volumetric attacks exceeding 1 Tbps plummeted by nearly 69% from Q2, possibly a reflection of law enforcement actions against four major Internet of Things (IoT) botnets earlier in the year. However, variants continue to emerge, proving that IoT botnets remain a durable, high-volume threat to network infrastructure.
Threat actors dramatically shifted their reflection and amplification tactics, abruptly abandoning CLDAP floods, which collapsed by 99.5% quarter-over-quarter. Instead, attackers pivoted heavily toward other connectionless protocols, driving a 215% surge in DNS amplification and a 122% increase in general UDP floods.
Attack targets broadened significantly across both industries and geographies, with the United States reclaiming the most-attacked position from China. Canada and Israel experienced sharp spikes in targeted attacks — jumping 10 and 7 spots respectively — while juggling geopolitical tensions, trade disputes, and contentious domestic events. At the same time, the operational focus shifted away from media organizations toward a wider array of industry targets, including consumer services, Internet infrastructure, and adult entertainment.
Q3 by the numbers: 8,200 DDoS attacks every hour
Across its network in the third quarter of 2026, Cloudflare autonomously mitigated 18.2 million network-layer DDoS attacks and 14.4 trillion HTTP DDoS requests. That works out to approximately 8,226 network-layer DDoS attacks per hour, or about 197,400 per day — one attack every 0.44 seconds. The quarter's mitigated traffic totaled 272.6 PB at the network layer and 95.1 PB at the HTTP layer.
More swarms, fewer giants
Short-burst, mid-range, high-count attacks — the operational signature of DDoS-for-hire "booter" services — accelerated this quarter. These attacks primarily targeted computer software, gambling and casinos, and information technology industries. Cloudflare autonomously mitigated 18.2 million network-layer DDoS attacks in Q3 2026, a +208% increase from the same quarter in 2025:
96% ended in under 10 minutes
98% stayed under 1 Gbps, more than enough to overwhelm a server or website
On the other hand, network-level hyper-volumetric attacks (those exceeding 1 Tbps) reversed course, dropping to 251 attacks in Q3 from 805 in Q2 — coinciding with law enforcement action in early 2026 that dismantled four of the largest IoT DDoS botnets: Aisuru, KimWolf, JackSkid, and Mossad.
Still, IoT-based botnets remain a durable high-volume threat as the ecosystem churns through new variants such as Dysphoria and Evooo1Bot. Mirai-classified mitigation peaked in August at 57.23 PB, representing 46.5% of all mitigated network-layer bytes in Q3, including four days — August 16, 19, 23, and 25 — that each cleared three petabytes. The quarter's longest sustained Mirai attack ran 49.7 hours between August 19 and August 21.
Vector shifts: the collapse of CLDAP and rise of UDP
The most dramatic vector shift of the quarter was downward. CLDAP (Connectionless Lightweight Directory Access Protocol) attacks — where small queries with a forged victim IP address trick public domain controllers (UDP 389) into reflecting massive, amplified responses back at the target — experienced a dramatic +580% quarter-over-quarter surge in the first half of the year before collapsing to just 0.05% of attacks in Q3.
Meanwhile, DNS amplification surged 215% to account for 3.43% of all network-layer attacks, exploiting open DNS resolvers in a similar reflection-and-amplification pattern to CLDAP: small spoofed queries, large replies directed at the victim. Other UDP floods climbed from 14.06% to 31.31% of network-layer attacks. UDP is a connectionless transport protocol, which makes it a convenient vehicle for raw volumetric attacks: attackers send large numbers of UDP packets to random or specific ports on the target, forcing the target to check for a listening application and respond, consuming its network and compute resources.
Most-attacked industry
While Media, Production & Publishing remained the most-attacked industry in Q3 2026, its overall share is roughly a quarter of its Q2 level, and the focus has moved across a wider set of industries. Internet rose from outside the top 10 to #6; Consumer Services and Adult Entertainment also climbed in, reaching #8 and #9 respectively.
Most-attacked locations
Geographic surges: Canada and Israel climb the ranks
Adding to an already turbulent period of bilateral trade disputes, Canada jumped from #16 to #6, driven by attacks against its Retail, Telecommunications, Service providers & carriers, and Marketing & advertising industries.
Israel moved 7 spots to take #10 as a result of sustained DDoS activity in mid-September. While this period was marked by contentious decisions ahead of parliamentary elections and the Rosh Hashanah holiday, there was also a massive, documented surge in hostile cyber warfare targeting Israel this year.
Top 10
The United States was the most-attacked location in Q3 2026, while China was number #2 and Indonesia rose into the top three at 2.93% of total attacks. The U.S.-China pairing at the top is consistent with the first half of 2026, when China finished #1 and the U.S. #2; the countries have traded positions as attention and attacker preferences shift.
Strengthening global defenses and helping to defend the Internet
Cloudflare's network is designed to absorb this kind of growth in DDoS threats. Every service on our network is protected by free, unmetered DDoS protection that runs at every one of our 330+ cities globally, backed by 500 Tbps of network capacity. Autonomy is the point: our systems detect and mitigate attacks without human intervention. And they need to, because as this quarter's distributions make clear, most attacks end long before a human analyst could see the alert, and the largest attacks still regularly exceed 1 Tbps at a cadence measured in hundreds per quarter.
To help hosting providers, cloud computing platforms, and Internet service providers identify and take down the abusive IP addresses and accounts that launch these attacks, we leverage Cloudflare's unique vantage point on DDoS attacks to provide a free DDoS Botnet Threat Feed for Service Providers.
Over 800 networks worldwide have signed up for this feed, and we've already seen great collaboration across the community to take down botnet nodes. For a continuously-updated view of attack trends across the Internet, visit Cloudflare Radar.
About Cloudforce One
Driven by a mission to help defend the Internet, Cloudforce One draws on telemetry from Cloudflare's global network — which protects more than 20% of the web — to drive threat research and operational response, protecting critical systems for millions of organizations worldwide.
October 16, 2026 was a good day for the cryptography community. A 25-year-old question about the math behind some of the Internet’s most widely used encryption was finally answered. The previously lost method used to create the widely-used NIST elliptic curves has been found.
In 2023, Filippo Valsorda created a bounty for answering the question, with a twist: if the solvers gave the prize to a nonprofit, it would be tripled, from $12,288 to $36,864. A group of engineers raised their hands to fund the bounty prize. Such a generous and thoughtful idea. And you guessed it! The solvers, a team of researchers at Anthropic, took Filippo up on it and donated the bounty to ISRG. ISRG is grateful for the generous support and we’re grateful because the answer itself strengthens confidence in cryptography that secures much of the web. A good day indeed.
What was the bounty? What was the answer? It’s a long story. TL;DR: The NIST elliptic curves, used in encryption across the Internet, were built from “seeds” that two NSA engineers generated in the late 1990s. Years later, nobody could remember exactly how they’d made them. Humans do what humans do, and without an answer, some people grew skeptical. That kind of doubt chips away at trust, which obviously isn’t great for cryptographic infrastructure. The answer turned out to be reassuring: the seeds came from an ordinary random number generator, seeded with the time.
What we love most about this story is that Filippo and our community wanted to uphold the public’s trust. We build and protect Internet infrastructure, and work to keep it secure every day. Filippo didn’t have to create this bounty, but he wanted answers for his fellow engineers and the public. The engineers who chipped in didn’t have to put up their hard-earned dollars, but they wanted to help put the speculation to rest. And the team at Anthropic didn’t have to spend time solving it, but enlisted Claude’s help in closing this cryptographic chapter of history.
Who do you know that is helping make the Internet better? Thank them! Many of them are paid to do this work, but they also do it on their own time because they care deeply. And so do we.
In the cryptography and security community, we are working every day to protect our teams, our organizations, our friends and family, and in ISRG’s case, billions of users online. Consider making a donation in honor of that work. You can give online or make your donation via stock, crypto, check, DAF, and more. Learn more in the Ways To Give section of our donation page.
John Wood, Henry de Valence, Ava Howell, Zack Voase, Lucy Sweet, Amir Omidi, Paul Crowley, Iain McGinniss, Nicholas Carlini, and Steve Weis, the team at Anthropic who solved it and chose to send the prize to ISRG. Read Anthropic’s writeup.
Amir Omidi, Chris Palmer, Colm MacCárthaigh, David Adrian, David Anderson, Filippo Valsorda, Jeff Hodges, Matt Green, Matthew McPherrin, Paul Kehrer, Ryan Sleevi, and Soatok, who chipped in their own money to fund the bounty.
Thank you for making the Internet more secure every day.
The Linux Plumbers Conference blog has a
report from the sched_ext microconference held in Prague.
Three main topics dominated the discussions
Priority inversion and how to handle it in sched_ext: lock holder and
lock waiter preemption, time slice extension, and making proxy execution
work together with BPF schedulers.
Paravirtualized scheduling: letting the host and guest schedulers
cooperate across the VM boundary, with sched_ext as the policy engine on
the host.
Device and topology-aware scheduling: using hardware feedback (Intel
HFI), device/accelerator locality and cache topology to drive task
placement.
A durable function is an AWS Lambda function that might run for minutes, days, or even up to a year. You build these functions with the Durable Execution SDK, which provides operations such as steps, waits, and parallel. A single durable execution might be spread across many Lambda invocations, with waits and retries in between. So observing a durable execution, made of many invocations, needs different tools. The question that you want answered is rarely “what did this invocation do?” It’s “how far did my durable execution get, which step failed, how many times did it retry, and how long did the whole thing take?”
After you run thousands of executions, the questions widen from one execution to all of them. Some questions are operational. Which step fails most often, and with which error? Which step causes the most retries? Did a step get slower after last week’s deployment? Other questions are about the business the workflow runs. Which customers did last night’s payment failures affect? How long does each manual approval step take? Of the orders that started, how many reached the payment step, and where did the rest stop? Answering these questions needs per execution telemetry data that includes relevant data such as status, timing, steps, and the input and output fields that you choose to emit.
Traditional Lambda observability works well for a single invocation. Lambda writes a log stream per invocation, so a durable execution that suspends four times writes to four separate log streams, interleaved with every other concurrent execution. Amazon CloudWatch metrics tell you the function’s error rate, but not which of your workflow’s steps is responsible. Distributed tracing, such as AWS X-Ray or OpenTelemetry, shows the timing of one execution. It isn’t built to answer questions across many executions, such as which step failed most often this week. For that, you need one queryable record per execution.
Today we’re introducing the Durable Execution Telemetry Exporter, an observability plugin for AWS Lambda durable functions. We’re also introducing the Durable Execution Telemetry MCP server, a Model Context Protocol (MCP) server that lets an AI coding agent query the telemetry data. The exporter is open source for TypeScript, Python, Java, and Go, in each language’s Durable Execution SDK repository. AWS provides the MCP server as open source in the aws-durable-execution-sdk-js repository.
With a one-line configuration change, you get a record of each execution, with every step, wait, callback, and invoke, including timing, retry attempts, status, and errors. The exporter delivers it to a destination you choose. There’s no custom instrumentation to write and no separate agent to run.
How the durable execution telemetry exporter works
The Durable Execution Telemetry Exporter is a plugin for the durable execution SDK. It runs inside your Lambda function, in the same process as your handler, and subscribes to the SDK’s instrumentation lifecycle. It doesn’t run in your request path.
On every invocation of a durable execution, the plugin builds a cumulative snapshot of that execution, rather than a delta or per-invocation view. Because the durable execution SDK replays your handler from the beginning on each resume and the SDK passes the checkpointed state to the plugin, the plugin can reconstruct the whole execution so far from any invocation. That snapshot is a single JSON document called a DurableExecutionTelemetryRecord:
Each record is complete on its own. One row in a table is one durable execution, which means the questions you ask (slowest step, most-retried step, executions that failed after the payment step) become ordinary queries instead of requiring you to correlate logs across streams.
Getting started
Install the plugin alongside the durable execution SDK:
That is the entire integration. With no configuration, the default LambdaLogExporter writes records as JSON to your function’s own CloudWatch log group. You don’t need to create any infrastructure or grant additional AWS Identity and Access Management (IAM) permissions, because your function already writes its own logs. You can query the result immediately with Amazon CloudWatch Logs Insights:
fields executionName, status, durationMs
| filter recordType = "DurableExecutionTelemetry" and status = "FAILED"
| sort durationMs desc
Choosing where records go
The plugin includes 13 destination exporters so you can send records where they are useful:
Destination
Exporter
Good for
Function’s own log group
LambdaLogExporter
Getting started, zero setup
Any CloudWatch log group
CloudWatchLogsExporter
Centralizing records across functions
Amazon Simple Storage Service (Amazon S3)
S3Exporter
Amazon Athena SQL, long-term retention
Amazon DynamoDB
DynamoDBExporter
Fast lookup by execution, live dashboards
Amazon Aurora
AuroraExporter
Joining workflow data with business data
Amazon Redshift
RedshiftExporter
Large-scale cross-function analytics
Amazon OpenSearch Service
OpenSearchExporter
Full-text search, dashboards
Amazon EventBridge
EventBridgeExporter
Alerting and remediation on failure
Amazon Data Firehose
FirehoseExporter
Fan-out to S3, Splunk, or third parties
Amazon Simple Queue Service (Amazon SQS)
SQSExporter
Decoupled downstream processing
Any OTLP endpoint
OTelExporter
Third-party observability platforms
Any HTTPS endpoint
HttpExporter
Custom backends and webhooks
Filesystem or Amazon Elastic File System (Amazon EFS)
FileExporter
Local development, EFS persistence
The plugin sends records to all configured exporters in parallel. This allows you to route data to different stores based on their characteristics, such as using a fast store for real-time lookups and a less expensive, high-capacity store for long-term storage:
import {
  durableExecutionTelemetry,
  S3Exporter,
  DynamoDBExporter,
  EventBridgeExporter,
} from "@aws/durable-execution-sdk-js-telemetry-exporter";

const telemetry = durableExecutionTelemetry({
  emitMode: "on-complete",
  samplingRate: 1.0,
  exporters: [
    new S3Exporter({ bucket: string }), // Use valid bucket name you own
    new DynamoDBExporter({ tableName: "durable-execution-telemetry-live" }),
    new EventBridgeExporter({}),
  ],
});
With the S3 exporter, the plugin writes records under Hive-style partitions (year=YYYY/month=MM/day=DD/) that an AWS Glue crawler discovers automatically, so Athena queries work without additional modeling:
SELECT op.name, COUNT(*) AS failures, AVG(op.durationms) AS avg_ms
FROM durable_execution_telemetry
CROSS JOIN UNNEST(operations) AS t(op)
WHERE status = 'FAILED' AND year = '2026' AND month = '06'
GROUP BY op.name
ORDER BY failures DESC;
Controlling frequency and content
Three settings govern what a production deployment costs and exposes.
emitMode determines when the plugin sends a record. The default, on-complete, emits once when an execution reaches SUCCEEDED or FAILED. Use on-failure for the lowest overhead when you only care about errors, or on-change when you want to watch executions progress in near real time.
samplingRate reduces frequency. The plugin derives the sampling decision from a hash of the execution ARN. The execution ARN is stable across replays, so the decision is deterministic: a sampled-in execution emits all of its records, and a sampled-out execution emits none. You never receive a half-recorded workflow.
content controls what leaves your function. By default, the plugin includes execution input and output as-is, which is convenient in development and often unacceptable in production. Pass a transform to redact:
Each destination supports different payload sizes: CloudWatch Logs events at 256 KB, DynamoDB items at 400 KB. Each exporter has a maxRecordSizeBytes, and when a record exceeds it the plugin truncates for one destination without affecting other destinations: operation results first, then whole operations oldest-first, then execution input and output last. The plugin never drops identity and timeline fields, and it marks a trimmed record truncated: true, so a truncated record is always distinguishable from a complete one. We recommend using content transforms to bound payloads deliberately rather than relying on truncation.
Querying execution history from an AI agent
Answering “why did last night’s batch fail” requires knowing which data store you configured, which query dialect it uses, and what the record schema looks like. DynamoDB PartiQL, Athena’s Trino SQL, Aurora PostgreSQL, Amazon Redshift, OpenSearch, and CloudWatch Logs Insights all differ.
The Durable Execution Telemetry MCP server removes that requirement. It’s a local stdio server that exposes your configured destination to any MCP-capable agent, including Kiro, Claude Code, and Cursor. Add it with one command:
Configuration is environment-only and credentials come from the standard AWS SDK provider chain, so there’s no state file and no secret. The server exposes five tools:
test_destination runs read-only connectivity checks. If a required variable is unset, it names the exact variable and returns without making any AWS call.
describe_schema returns the record schema, query dialect, and row cap for whichever destination is configured. Agents should call this before writing a query.
list_executions filters by status, function name, and time range with no query language involved. This handles most questions.
get_execution fetches one record by execution ARN.
query handles questions the filters cannot express.
You ask a question and the agent picks the tools:
Which steps in order-processor failed most often in the last 24 hours, and what was the average retry count?
On the SQL destinations, write each query as a SELECT statement, or as a WITH statement that ends in a SELECT. These are the only forms the server runs. It checks a query before it makes any AWS call, so a statement that would change data never reaches your destination. On the CloudWatch Logs destinations, the Logs Insights query language has no statements that write data. So every query through the server is read-only.
Best practices and considerations
Choose operationDetail deliberately. The default, top-level, records only top-level operations and produces the same set of operations no matter when a record is emitted. full-tree includes children of contexts such as map items and parallel branches, but by default the durable execution backend prunes finished contexts’ children from the state passed to later invocations. To keep the full tree across a suspend and resume, also set pluginsConfig.childOperationsDepth on withDurableExecution. That preservation has a cost: it forces a replay pass over each preserved context on resume, so enable only the depth you need.
Choose operation names that your destination can query. The plugin uses names verbatim as keys and identifiers and never sanitizes them. A . in a name is a field-path separator in CloudWatch Logs Insights and OpenSearch. Letters, digits, -, and _ are portable everywhere.
Understand what the plugin cannot see. The Durable Execution Telemetry Exporter runs inside your function, so it can only emit records when your function is invoked. Terminal states that originate in the Lambda service without an invocation never reach the plugin: STOPPED from a manual stop, and TIMED_OUT when the execution timeout is exceeded. For complete lifecycle coverage, subscribe to Lambda durable execution lifecycle events on the default Amazon EventBridge bus and update your destination from a small handler:
Account for the cost of the destination. The plugin adds at most one export each time it emits a record, because it sends only the latest of any updates that pile up. Each record is a complete snapshot, and the latest supersedes all earlier ones. If updates arrive faster than an exporter can handle, the plugin drops the intermediate snapshots. The charges that matter are the ones your destination incurs: CloudWatch Logs ingestion, DynamoDB writes, Aurora capacity, and so on. Combine samplingRate and emitMode to control them.
Conclusion
The Durable Execution Telemetry Exporter gives AWS Lambda durable functions an observability model that matches how they run: one complete record per execution, sent to a destination that fits your team. The Durable Execution Telemetry MCP server lets an AI agent answer questions against that data directly.
To get started with durable functions, see the AWS Lambda Developer Guide. For the plugin’s full exporter reference, configuration options, and an AWS Cloud Development Kit (AWS CDK) stack that deploys every destination for testing, see the package README.
Accelerating API adoption while reducing operational overhead is a challenge that every growing organization faces. For Revinate, a hospitality provider serving over 12,500 hotels worldwide and powering more than 1.25 billion guest profiles, Amazon API Gateway became the foundation of their solution.
Revinate empowers hoteliers to connect directly with guests at every touchpoint, driving $24 billion in lifetime direct revenue through an AI-powered Customer Data Platform (CDP) that helps reduce reliance on online travel agencies (OTAs) and deliver data-driven insights.
With the expansion of CDP capabilities, Revinate needed to expose rich guest data through APIs, so that hotel properties and partners can programmatically access guest profiles, reservation data, and other critical hospitality information.
Business need: Evolving API infrastructure to match growth
As Revinate expanded its CDP capabilities and began exposing guest profile and reservation data through APIs, the limitations of managing API infrastructure in-house became clear. Each new partner integration required manual provisioning, custom security configuration, and ongoing maintenance. The team needed an API gateway solution that could scale with growing partner demand without adding operational burden. Rather than building and maintaining a self-hosted solution, Revinate wanted an approach that would open up engineering time, streamline partner integrations, and align infrastructure costs with actual usage. The team identified four key business drivers:
Operational efficiency and agility – Accelerate API deployment cycles and reduce time spent on infrastructure maintenance so the engineering team can focus on building features that directly serve customers.
Faster partner and developer onboarding – Helping external developers and partners to discover and adopt Revinate’s APIs required a faster, more self-service experience.
Growth aligned costs – Infrastructure costs needed to scale proportionately with revenue generation. An on-demand pricing model, where costs flex with actual API usage rather than fixed overhead, was essential to support sustainable growth. Equally important was the ability to attribute API costs per consumer, enabling transparent cost allocation across hotel properties and partners.
Enhanced security and compliance – API security controls including authentication, authorization, rate limiting, and threat protection. Meeting compliance requirements and maintaining customer trust demanded strong security without adding complexity to the development workflow or requiring the team to build and maintain custom security infrastructure.
These requirements shaped the team’s evaluation of available solutions.
Evaluating alternatives
When evaluating API gateway solutions, the team translated the business drivers into four core technical requirements. On-demand pricing was essential to align infrastructure costs with actual API usage and enable per-consumer cost attribution. Authentication federation allows integration with Revinate’s existing identity provider, so partners can onboard faster without building custom auth infrastructure. Rate limiting was needed to protect backend services and enforce fair usage across hotel properties and partners as the API program scales. Finally, strong security, including threat protection, audit logging, and access controls, was required to meet compliance requirements for protecting sensitive guest data.
The engineering team evaluated three approaches. Each approach came with distinct tradeoffs across cost, flexibility, and operational burden.
Self-managed API management
Deploying a self-managed API gateway would provide flexibility and avoid licensing fees, but requires ongoing infrastructure management, security patching, scaling, and monitoring. The team would also need to build a custom developer portal from scratch.
Custom-built
Building a proprietary API gateway tailored to Revinate’s exact needs offers maximum control but demands significant upfront development investment and ongoing maintenance. Every capability, including routing, authentication, rate limiting, and documentation, would need to be built and maintained in-house, diverting engineering resources from core hospitality platform features.
Enterprise API management platforms
Enterprise platforms offer comprehensive out-of-the-box features, but introduce vendor dependencies, higher costs, and fixed-term licensing models where costs misalign with revenue growth.
All three approaches shared a common drawback: they would divert resources, whether engineering time, budget, or both, toward capabilities that don’t differentiate Revinate’s product, delaying time-to-market for features that directly serve hotel customers.
The solution: Amazon API Gateway with Developer Portal
Revinate needed the comprehensive capabilities of an enterprise API management platform without the fixed-term licensing, vendor dependencies, and operational overhead. Amazon API Gateway, combined with the newly released Amazon API Gateway Portal, delivered exactly that, aligning with both the technical requirements and business objectives that shaped the evaluation.
Fully managed infrastructure
Amazon API Gateway removes the need to manage underlying infrastructure, so the engineering team can focus on the core hospitality solution rather than API gateway operations.
Native AWS integration
Amazon API Gateway provides native integration with other AWS services, including Amazon Elastic Kubernetes Service (Amazon EKS) for backend services and AWS Lambda authorizers for federated authentication with an external identity provider. This allows Revinate to authenticate API consumers against the existing identity provider infrastructure with minimal development effort.
Infrastructure as code with Terraform
The team maintains strict infrastructure-as-code practices, using Terraform exclusively for all production deployments. The AWS provider for Terraform enables defining the Amazon API Gateway configuration, including REST APIs, stages, usage plans, and authorizers as version-controlled code. This approach verifies consistency across environments, enables peer review of infrastructure changes, and provides complete audit trails for compliance requirements. The declarative nature of Terraform enables rapidly iterating on the API Gateway configuration during development while maintaining confidence in production deployments.
Cost-effective pay-per-use model
Amazon API Gateway’s pay-per-use pricing model aligned perfectly with Revinate’s growth strategy. During the initial rollout phase, costs remained minimal and scaled naturally as new API consumers onboarded. Usage plans allow Revinate to track and attribute costs per consumer, providing clear visibility into which hotel properties and partners drive API usage. This per-consumer cost attribution, combined with tiered pricing that scales from tens to hundreds of customers, replaced fixed annual licensing fees that required upfront investment regardless of actual usage.
Managed Developer Portal
The November 2025 release of Amazon API Gateway Portal provided a fully managed, AWS-native Developer Portal that served as the central hub for API discovery, documentation, and governance. This removes months of custom development work that building a comparable solution would require.
Developers can use the managed portal to:
Set up a branded Developer Portal in minutes rather than months.
Provide hotel property developers with self-service API discovery and interactive documentation.
Maintain centralized control over API documentation freshness and access governance.
Deliver a professional developer experience that accelerates customer onboarding from weeks to days.
Strong security
API Gateway provides built-in security features that meet stringent requirements for protecting sensitive guest data:
OAuth2 client credentials for machine-to-machine (M2M) authentication.
Authorization logic using AWS Lambda authorizers integrating with an external identity provider of choice.
Request throttling and quota management to prevent abuse.
Integration with AWS WAF and Amazon CloudFront for layered protection against common web exploits and DDoS threats.
Comprehensive audit logging through AWS CloudTrail for compliance and access tracking.
Real-time observability through Amazon CloudWatch metrics and dashboards, with support for streaming to third-party observability platforms.
Architecture overview
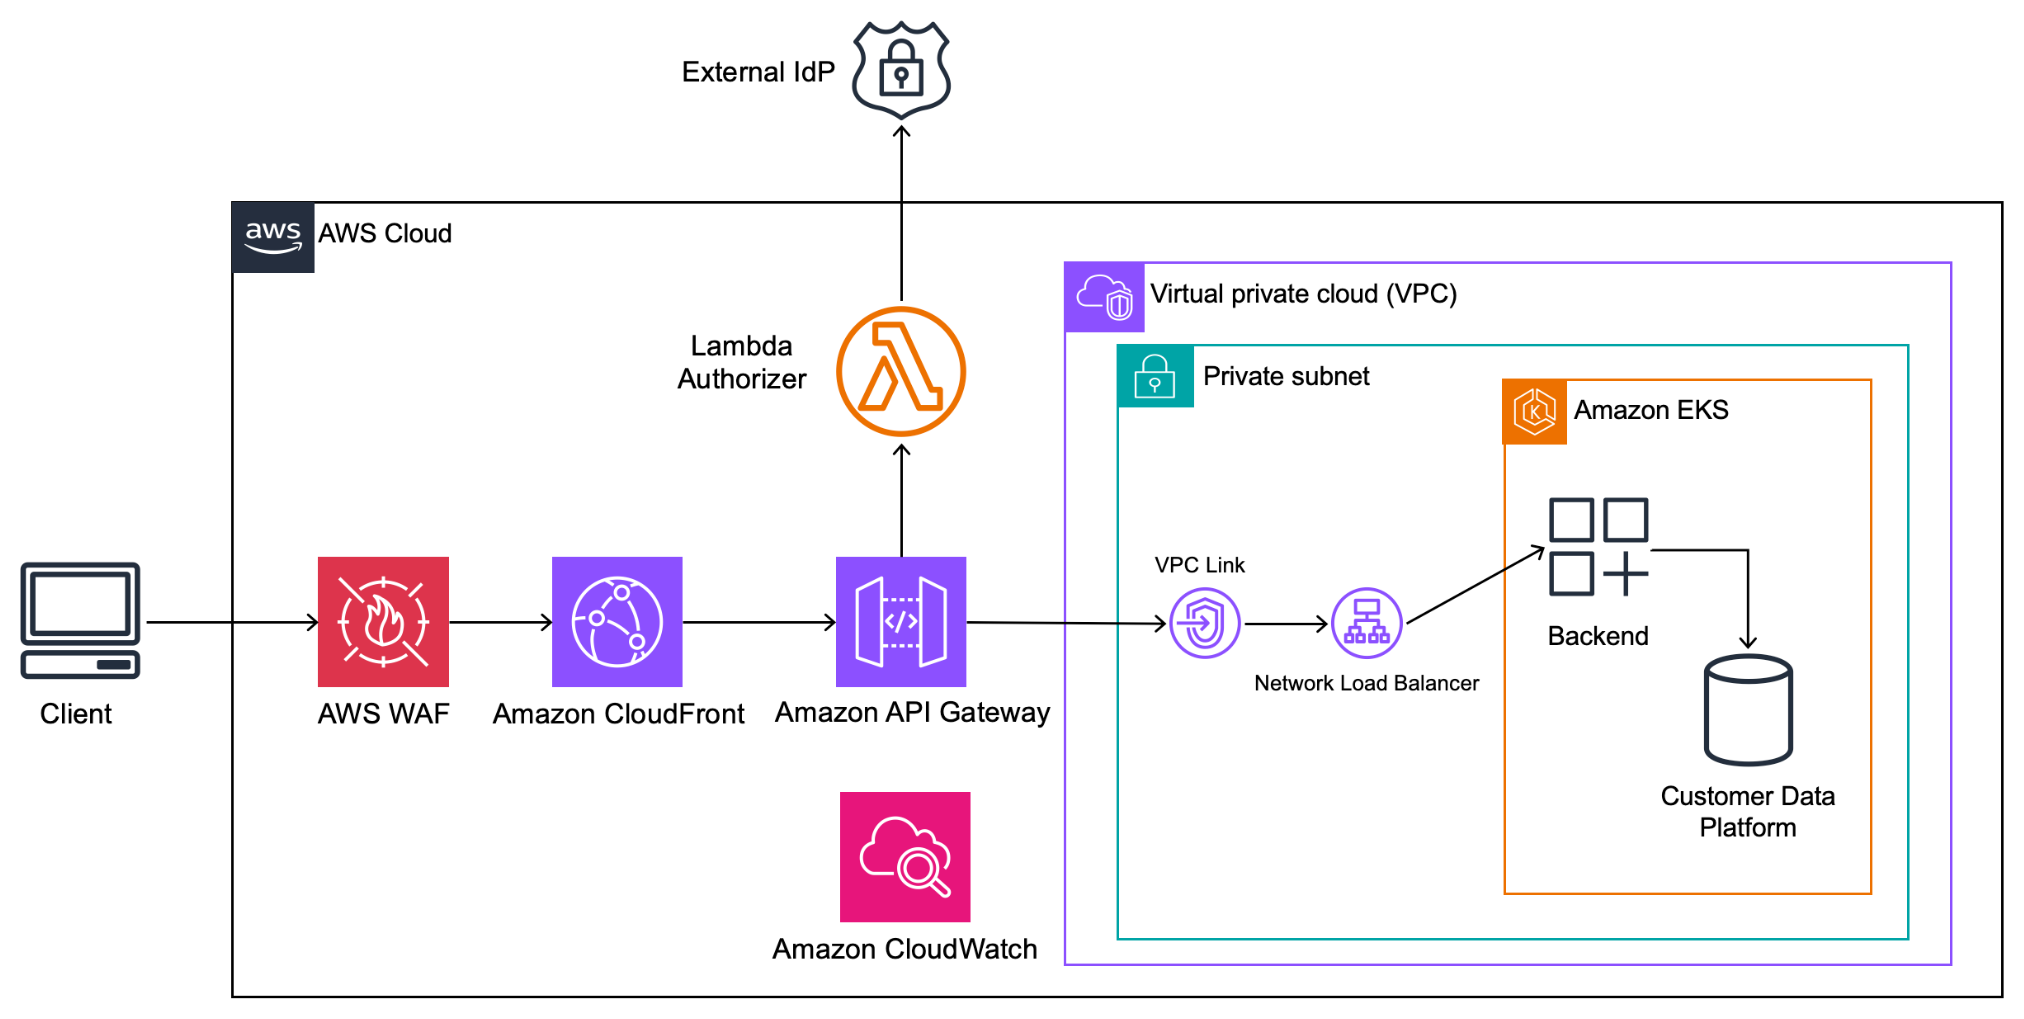
The solution uses a modern, scalable AWS architecture designed to serve hotel properties globally. Hotel properties access the platform as API consumers through Amazon CloudFront for edge caching and low-latency responses, with AWS WAF providing comprehensive protection against common web threats and bots. Requests flow through Amazon API Gateway, which serves as the unified entry point for API operations. Lambda authorizers handle authentication and authorization by integrating with an identity provider (IdP) to provide secure, token-based access control for each request. After authentication, API Gateway routes traffic to backend services running on Amazon EKS, providing the flexibility and scalability needed for containerized microservices. The EKS application layer orchestrates requests to the Customer Data Platform.
Figure 1: Architecture diagram showing the end-to-end flow from hotel property consumers accessing the Amazon API Gateway Portal, through Amazon API Gateway, to backend services running on Amazon EKS.
Connecting API Gateway to EKS
A critical design decision emerged: how to securely and efficiently connect API Gateway to backend services in Amazon EKS while keeping traffic within the AWS backbone network using VPC Link. The team evaluated four options:
Option 1: NGINX ingress controller: Route traffic through a Kubernetes-native NGINX Ingress Controller with a Load Balancer service.
Pros: Highly customizable routing, flexible header manipulation, consistent with common Kubernetes patterns.
Cons: Introduces an additional hop (Amazon API Gateway → LB → service).
Option 3: Target group binding: Directly bind Amazon EKS pods to Network Load Balancer (NLB) Target Groups using the AWS Load Balancer Controller’s TargetGroupBinding feature.
Pros: Removes ingress controller overhead, lowest latency, native AWS integration, cost-efficient (shared NLB across multiple Target Groups), fine-grained control over health checks and scaling.
Cons: More complex initial setup, less Kubernetes-native (more AWS-specific), different applications will need individual NLB.
Option 4: LoadBalancer service: Expose each service directly via a Kubernetes LoadBalancer service (NLB/ALB).
Pros: Most straightforward setup, minimal routing complexity, no ingress controller needed.
Cons: No path-based routing, costly at scale (each service requires its own load balancer), limited observability, requires TLS offloading configuration, different applications will need individual NLB.
The team selected Target group binding because it effectively balances performance, cost-efficiency, and AWS-native integration. By removing the extra hop introduced by traditional ingress controllers, this approach provides direct control over Target Groups and health checks while maintaining sub-second latency at scale.
Security implementation
The API Gateway implementation uses OAuth 2.0 client credentials flow with an external identity provider, delivering strong authentication for machine-to-machine (M2M) communication. This approach provides secure, scalable access control as Revinate onboards new hotel properties and partners.
API Gateway enforces usage plans with configurable throttling and quota limits, for fair usage and protection against abuse.
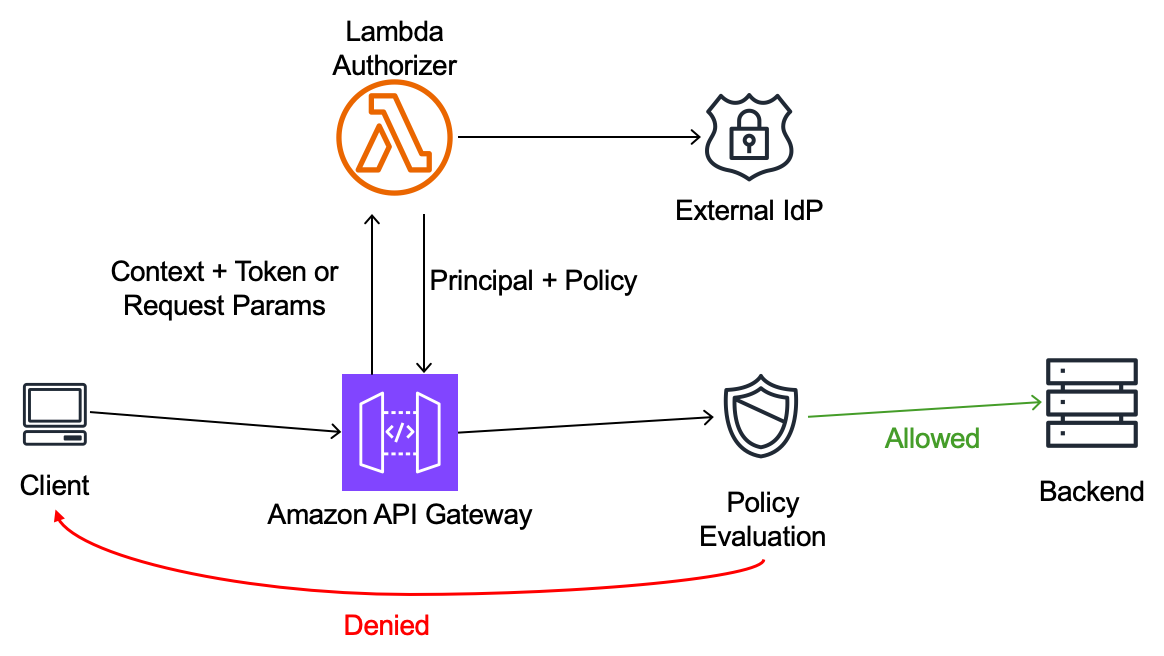
Figure 2: Sequence diagram illustrating the OAuth 2.0 authentication flow using AWS Lambda authorizers.
AWS Lambda authorizers take the caller’s identity as the input and return an IAM policy as the output. This architecture provides flexibility to implement sophisticated authorization logic while maintaining the simplicity of the API Gateway managed infrastructure. The team also deploys and manages the Lambda authorizer functions through Terraform, maintaining infrastructure as code (IaC) standards.
Developer Portal experience
The Amazon API Gateway Portal serves as the central hub for the API operations, providing developers using APIs with a streamlined experience.
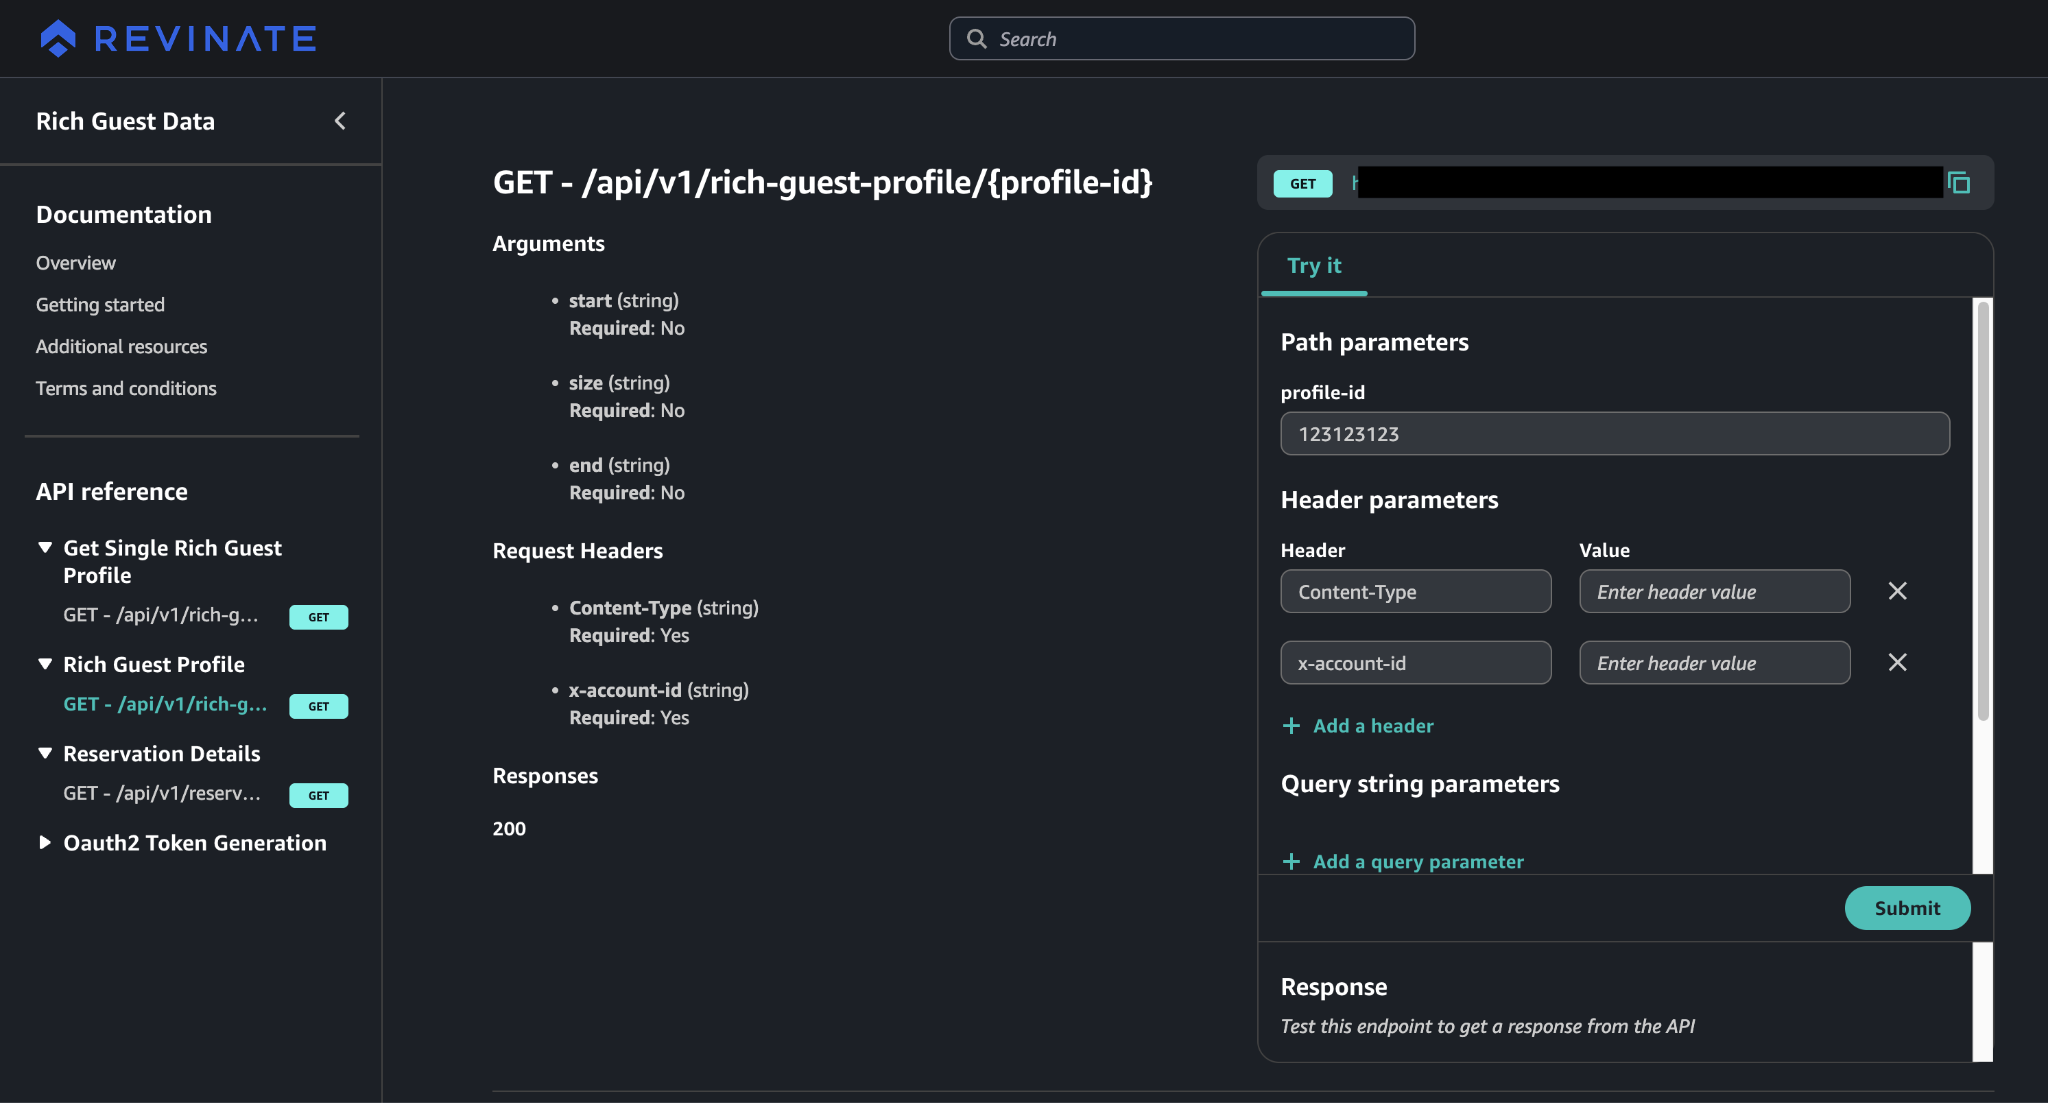
Figure 3: User interface flow showing the developer journey through the Amazon API Gateway Portal, including API discovery, interactive documentation with try-it-now functionality, and subscription management.
Developers can:
Browse available REST APIs with comprehensive documentation.
Test API endpoints directly in the portal with interactive examples.
Access code samples and integration guides.
This self-service model reduced burden on support while accelerating customer time-to-value.
Results and benefits
The implementation of Amazon API Gateway and the Developer Portal delivered significant qualitative benefits across operational efficiency, developer experience, and business scalability.
Reduced operational overhead
By choosing a fully managed API gateway, the engineering team avoided the burden of maintaining, scaling, and troubleshooting self-hosted infrastructure. With the fully managed API gateway, the team can focus on core platform innovations that directly benefit hotel customers rather than undifferentiated gateway operations.
Improved developer experience
The centralized Developer Portal transformed the integration experience for hotel properties and partners. Self-service API discovery and interactive documentation reduced onboarding time from weeks to days. Developers consistently praised the professional portal experience and comprehensive documentation.
Accelerated customer onboarding
With the Developer Portal’s self-service capabilities, new customers can discover APIs and begin integration without waiting for manual provisioning or support intervention. This self-service approach positions Revinate to scale API access to hundreds of hotel properties and partners as demand grows.
Enhanced governance and control
The solution centralized control over API documentation, versioning, and access policies, verifying consistency across customer integrations. A single source of truth for API specifications removes documentation drift and reduces integration errors. Managing infrastructure through Terraform verifies changes follow proper review and approval processes.
Cost optimization
The pay-per-use pricing model aligns costs with actual usage and revenue generation. Usage plans and API keys provide per-consumer cost attribution, giving Revinate clear visibility into infrastructure spend by customer. As usage scales, tiered pricing verifies predictable cost growth that tracks with business value, replacing fixed licensing models that require upfront investment regardless of adoption.
Positioned for growth
The API layer, from Amazon API Gateway to the Developer Portal, scales automatically to meet demand without capacity planning or operational intervention. The team can confidently pursue growth targets knowing the API infrastructure will scale automatically.
Enhanced security posture
Amazon API Gateway provides strong security capabilities built into the platform, including centralized authentication and authorization mechanisms, request throttling and rate limiting to protect against abuse, and automatic threat protection through AWS Shield integration. Built-in security capabilities remove the need to build and maintain custom infrastructure while verifying consistent security policies across API endpoints. The centralized approach reduces the attack surface and provides comprehensive audit trails through CloudWatch integration, so the team can maintain robust security without additional operational overhead.
Key takeaways
The successful implementation of Amazon API Gateway and the Amazon API Gateway Portal offers valuable lessons for organizations exposing APIs to external customers and partners:
Managed services accelerate time-to-market – By using fully managed infrastructure and the new Amazon API Gateway Portal, the team avoided months of custom development work and launched the API program faster than would have been possible with self-managed alternatives.
Developer experience drives adoption – The professional, self-service Amazon API Gateway Portal significantly reduced friction in the customer onboarding process, so API access can rapidly scale as new hotel properties and partners onboard.
Infrastructure as code verifies consistency – Using Terraform for all production deployments provided the infrastructure team with version control, peer review, and audit trails while maintaining deployment consistency across environments.
Pay-per-use aligns costs with value – For organizations in growth mode, pay-per-use pricing removes the risk of overcommitting to fixed costs before achieving product-market fit with API offerings.
OAuth 2.0 delivers strong security at scale – Implementing OAuth 2.0 client credentials flow with an external identity provider enables a robust, scalable authentication foundation that grows securely alongside its expanding customer base.
Native AWS integration reduces complexity – For organizations already running on AWS, API Gateway’s native integration with services like EKS, Lambda, and CloudWatch minimizes architectural complexity and operational overhead.
Future enhancements
With the outbound API program successfully launched, the team is planning to extend API Gateway to inbound APIs, where partners push data into Revinate’s service. This will provide consistent security, monitoring, and governance across API traffic.
The team is also exploring advanced API Gateway features including request and response transformation, caching for improved performance, and deeper integration with AWS WAF for enhanced security against evolving threats.
Conclusion
Choosing Amazon API Gateway with the Developer Portal demonstrates how fully managed services can accelerate innovation while reducing operational complexity. By embracing AWS-native solutions and infrastructure-as-code practices, Revinate built a scalable, secure API program that supports growth as more customers get onboarded.
As the hospitality industry continues its digital transformation, this API-first approach positions them to empower hoteliers with the data and integrations needed to deliver exceptional guest experiences and drive direct revenue growth.
Next steps
Whether you’re in hospitality, software as a service (SaaS), healthcare, or any industry where partners and customers need programmatic access to your service, the pattern Revinate followed is broadly applicable. Start by mapping your business drivers to concrete technical requirements. This grounds your API gateway choices in outcomes, not only features. From there, explore Amazon API Gateway’s REST and HTTP API options to find the right fit for your traffic patterns and integration needs. Use the Amazon API Gateway Portal to give your developers a self-service onboarding experience from day one. If you’re already running workloads on AWS, the native integration with services like EKS, Lambda, and CloudWatch means you can build on your existing architecture rather than introducing new operational complexity. For teams that follow infrastructure as code practices, the Terraform AWS Provider for API Gateway helps you to define your entire API configuration as version-controlled code. To get started, visit the Amazon API Gateway documentation or reach out to your AWS account team for architecture guidance tailored to your use case and scale.
In regulated industries, there’s no room for a move fast and break things approach, especially when AI agents are handling sensitive customer communications data. In this post, we show how Smarsh, a leading archiving and compliance platform for communications intelligence, used the AWS Well-Architected Framework’s Agentic AI Lens to conduct a rigorous, evidence-based review of its first agentic workload. The Agentic AI Lens is available today as prescriptive guidance, though it is not yet selectable as a lens in the AWS Well-Architected Framework.
To operationalize the review, Smarsh built a custom skill for Claude, Anthropic’s AI assistant. The skill assessed the workload against all 150 best practices in the lens, pulling evidence directly from the workload’s GitHub repository and producing a comprehensive review workbook in hours rather than days. In this post, we walk through the skill’s architecture, the assessment methodology, how the team validated the skill itself, and how the resulting findings strengthened Smarsh’s engagement with its AWS account team.
About Smarsh
Smarsh is a recognized global leader in electronic communications archiving and digital communications governance. For over 20 years, the multinational software as a service (SaaS) company has enabled more than 7,000 organizations, from small businesses to large multinational financial institutions, to capture, retain, monitor, and analyze communications across 100+ channels, including email, mobile, voice, video, chat, and AI assistants, at scale. The company’s enterprise archive business runs on Amazon Web Services (AWS), and its next generation of AI capabilities are being built on Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale, with any framework or model. Smarsh uses AgentCore’s runtime, gateway, registry, and identity capabilities to power these solutions. A 2025 AWS Partner of the Year Award winner, Smarsh holds a deep partnership with AWS.
Prerequisites
To follow along with the approach described in this post, you need the following:
An AWS account with access to Amazon Bedrock and Amazon Bedrock AgentCore.
Familiarity with the AWS Well-Architected Framework and its lens model.
A GitHub repository containing your agentic workload’s source code, infrastructure definitions, and documentation.
Access to Claude (Anthropic’s AI assistant) with the ability to install custom skills.
The challenge: A lens you can read, but not run
Smarsh operates in a highly regulated industry where compliance and security are paramount. Every agentic solution must pass a Well-Architected review before it reaches an end customer. So when a Smarsh architect set out to review the company’s first multi-agent workload, the natural choice was the AWS Well-Architected Framework’s Agentic AI Lens. That workload is an intelligent agent review system for compliance alerts built on the runtime, gateway, registry, and identity capabilities of Amazon Bedrock AgentCore.
The Serverless Applications Lens and other lenses can be added directly in the AWS Well-Architected Tool. The Agentic AI Lens, by contrast, existed only as published documentation: 150 best practices across 41 questions and six pillars, each with a risk level and a desired outcome, but with no way to run the review natively on the console. That left two apparent options: a multi-day manual effort in which every reviewer structured the assessment differently, or waiting for console support. Smarsh chose a third: make the lens executable, in a way every future workload could reuse.
Solution architecture: The lens as data, the reviewer as a skill
Smarsh packaged the review process as a Claude skill: a versioned bundle of instructions, reference data, and executable scripts that Claude discovers through a frontmatter description and loads on demand. Progressive disclosure keeps the token cost near zero until a review is actually requested. The skill has three components:
lens_data.json – All 150 best practices from the published lens documentation, extracted into a structured JSON dataset: best-practice ID, pillar, review question, title, risk level (90 High, 59 Medium, 1 Low), and desired outcome. Risk levels were cross-validated against the lens appendix to catch extraction errors. This dataset is the single source of truth, and the skill is instructed never to invent or renumber items.
assessment-guide.md – A five-value status rubric (Compliant, Partially Compliant, Non-Compliant, Not Applicable, and Not Reviewed), an evidence-gathering checklist, per-pillar signals to look for, and a set of honesty rules. The checklist covers README and architecture docs, decision records, infrastructure as code, continuous integration and continuous delivery (CI/CD) workflows, and test and evaluation suites. Every status must cite evidence found in the repository, items with no signal are marked Not Reviewed rather than guessed, and the same underlying fact must produce a consistent status wherever it appears across pillars.
build_report.py – A deterministic Python script (openpyxl) that renders the model’s assessment into a formatted workbook. The generator validates its input, so unknown best-practice IDs or invalid statuses abort the build and hallucinated items cannot silently ship. The output includes per-item status with data-validation dropdowns and conditional formatting. It also provides columns for cited evidence, gaps, and remediation, plus a summary sheet whose pillar counts and high-risk exposure tracker are live COUNTIF formulas rather than hardcoded numbers.
The assessment contract between the reasoning and the rendering is in a single JSON document:
{
  "AGENTSEC08-BP01": {
    "status": "Partially Compliant",
    "evidence": "Two-stage input validation (JSON Schema + Pydantic); 5 MB payload cap; typed prompts.",
    "gap": "No prompt-injection screening on message content.",
    "remediation": "Add injection screening; treat communication text as untrusted data in prompts."
  }
}
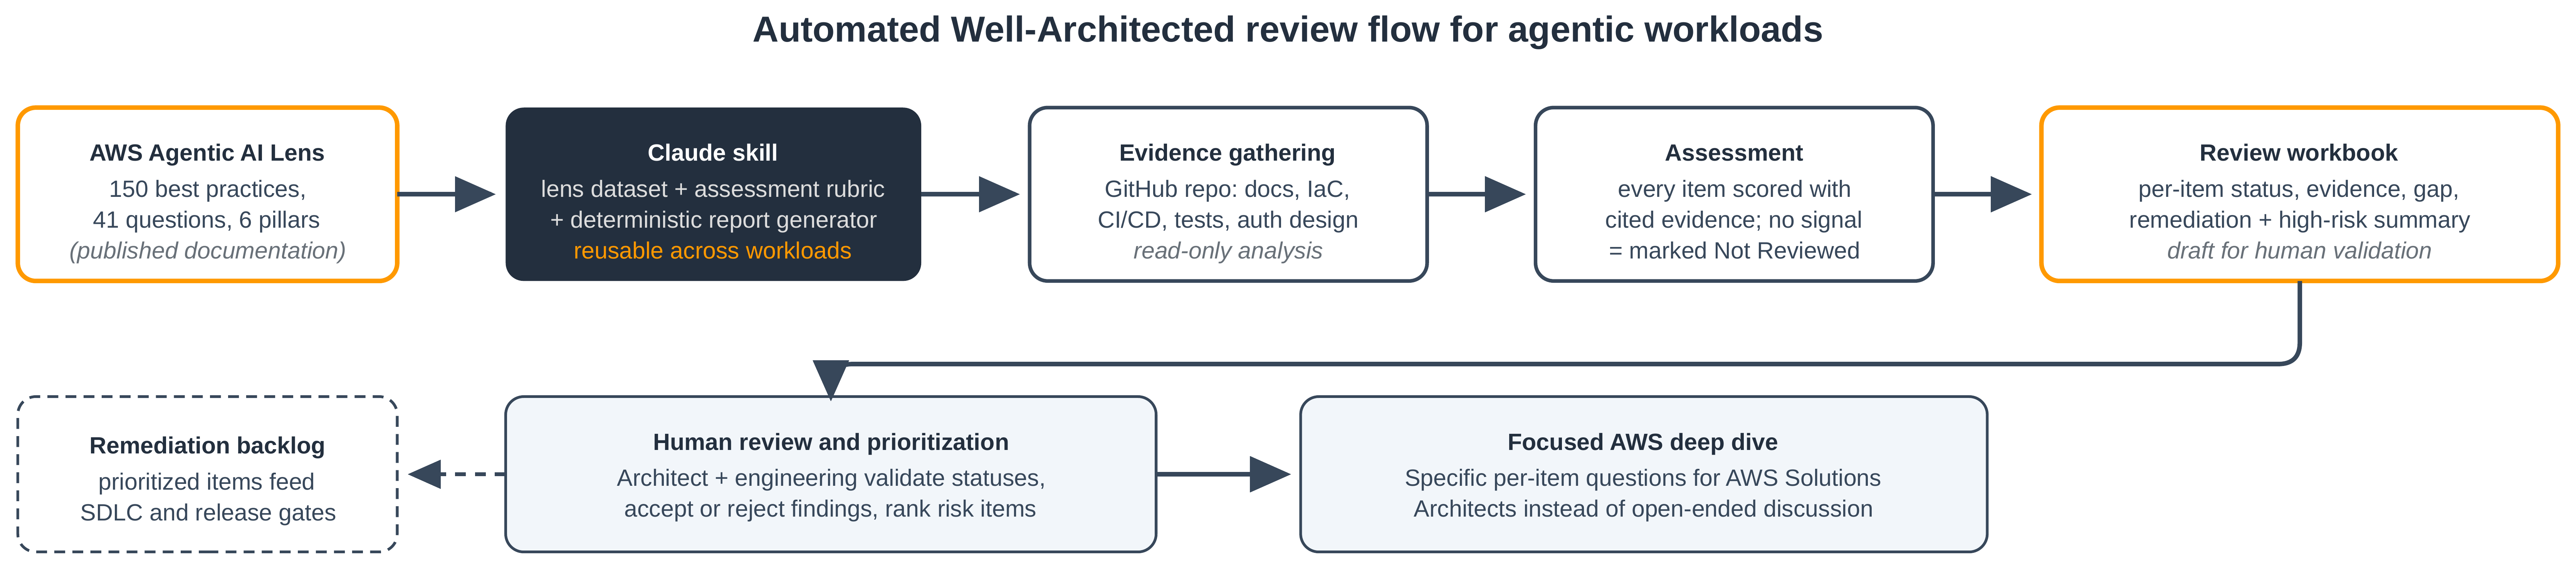
Running a review is a one-line request: point Claude at a repository and ask for a Well-Architected review. From there, the skill drives the following workflow:
Claude loads the skill and reads the frontmatter description to understand the review scope and methodology.
The skill pulls the lens_data.json dataset containing all 150 best practices across six pillars.
Claude gathers evidence read-only from the target repository: README, architecture docs, infrastructure-as-code, CI/CD workflows, and test suites.
The skill assesses all 150 items against the gathered evidence, applying the five-value rubric and honesty rules from assessment-guide.md.
Claude calls build_report.py to generate the formatted workbook, validating row counts and flagging blank statuses.
The skill returns an executive summary of the top high-risk gaps.
Human reviewers validate findings, feed a remediation backlog, and surface open system questions for a focused AWS deep dive.
Figure 1: From published lens documentation to an evidence-backed review workbook
Testing the tester: Evaluating the skill before trusting it
Smarsh evaluated the skill before relying on its output. The team built two synthetic fixture repositories: a moderately mature LangGraph-style workload and a deliberately rough proof of concept, complete with hardcoded credentials and a runaway-cost incident in its history. The team ran reviews both with and without the skill. Each run was graded against eight verifiable expectations per fixture: all 150 lens items present, no blank statuses, evidence cited for every definitive status, honest calibration, and fixture-specific findings such as the hardcoded credential being flagged. With the skill, runs passed 16 of 16 expectations. Baseline runs without it passed only 8 of 16, producing ad-hoc 18–39 item checklists with no lens traceability. The eval set ships inside the skill, so regression testing continues as the skill evolves.
What the first review found
Against the real workload, the skill read the repository’s architecture and authentication documentation, AWS Cloud Development Kit (AWS CDK) infrastructure definitions, GitHub Actions workflows, registry and gateway design records, and test suites. The skill then assessed all 150 items in hours. The workbook showed a credible mix of strengths and gaps. Strengths included per-agent AWS Identity and Access Management (IAM) execution roles scoped to named runtime Amazon Resource Names (ARNs) and SigV4-signed Model Context Protocol (MCP) calls through AgentCore Gateway, a capability of Amazon Bedrock AgentCore. The workbook also recorded schema-validated inputs with typed error contracts, exported decision audit trails, and continuous quality monitoring through AgentCore online evaluations. High-risk gaps included the gateway ingress authorizer running with authentication disabled under a documented risk acceptance, no prompt-injection screening on bad actor-influenced message content, rate limiting recorded as a TODO, and no automated cost controls. Each gap was tied to the lens item, the evidence, and a recommended remediation.
Next, the Smarsh architect brought in the engineering team. Together they triaged the findings, validating statuses against what the team knew, accepting or challenging results right in the workbook, and ranking the remediation backlog. Engineering’s input reshaped the review: several items collapsed into one anomaly-detection epic, and a single finding was upgraded once the team pointed to evidence the repository had overlooked. Dependency scanning was already running on every pull request.
Sharper questions, better AWS engagement
Triage surfaced a class of gaps no repository can answer: system-semantics questions about the AWS services themselves. Rather than booking a general architecture review, the team built a focused agenda for its AWS Solutions Architects, mapping each question to the checklist item it would close. The agenda covered:
The durability and consistency of AgentCore runtime, a capability of Amazon Bedrock AgentCore, as a session checkpoint store.
The retry and idempotency semantics of the InvokeAgentRuntime API.
Break-glass patterns for halting agent invocations.
Amazon Bedrock Guardrails patterns for screening untrusted content.
Penetration-testing rules of engagement for Amazon Bedrock AgentCore.
Amazon GuardDuty and AWS CloudTrail coverage for agentic-runtime threat detection.
The deep dive became a working session with a definition of done.
Why AWS
The security and compliance posture of Amazon Bedrock and Amazon Bedrock AgentCore, spanning runtime, gateway, registry, identity, and evaluation capabilities, meets the bar Smarsh’s regulated customers expect. The AWS Well-Architected Framework already anchors how Smarsh evaluates workloads. Extending it to agentic AI through the published lens, and pairing automated reviews with AWS Solutions Architect expertise to close the hard gaps, is a natural continuation of how the two teams work together.
Results and expected outcomes
These numbers reflect Smarsh’s first internal uses and the outcomes the team is tracking toward.
Review effort – A complete 150-item, evidence-cited draft in hours instead of a multi-day manual effort, with human time refocused on validation and prioritization.
Comparable reviews – Every workload produces the same standardized workbook, which Smarsh expects to translate into faster security approvals and improved time-to-market for agentic solutions.
Sharper use of AWS expertise – Instead of broad discussions, AWS engagements became itemized working sessions, each mapped to a specific best-practice gap.
What’s next
Publish the skill internally as the standard evaluation tool for Smarsh agentic workloads. It has been contributed to the company’s internal AI-SDLC plugin marketplace and has already been run against a second, architecturally different agentic repository.
Bake reviews into the software development lifecycle so well-architected checks run continuously during development, not as a one-time gate at the end.
Enforce governance by making the review workbook required evidence in Smarsh’s project milestone and gate process before agentic workloads reach production.
Expand the lens-as-data pattern to other AWS Well-Architected lenses and additional repositories, eventually covering the broader application portfolio.
Conclusion
The gap Smarsh hit, prescriptive guidance published faster than console tooling can absorb it, is one many customers will meet as agentic AI best practices evolve. The answer generalizes: treat the lens as data, encode the reviewer’s discipline as a skill with enforced honesty rules, validate the tool with its own evaluation suite, keep humans on judgment, and let findings drive precise conversations with AWS. A review that once implied days of manual effort is now a repeatable capability the whole organization can run, before, not after, an agentic workload meets a regulated customer.
Contact your AWS account team to schedule a Well-Architected review of your own agentic workloads.
We’d love to hear how you’re approaching Well-Architected reviews for your own agentic workloads. Share your experience in the comments, or reach out to your AWS account team to get started.
There is not a broad selection of mature, open-source web-browser engines
for Linux users. Most of the browsers available for Linux are based on one of
just three projects: Chromium’s Blink, Firefox’s Gecko, or WebKit. A new entrant would
generally be seen as a welcome alternative, but the recent campaign to push one
of the LLM-written Nordstjernen browsers
into Debian and Arch Linux has raised some questions about
the project’s development and security processes.
The Redox OS project, which is a
Unix-like microkernel-based operating system written in Rust, has published a report on the work
that it has done in the last year to implement io_uring-like I/O.
Last year, the Redox team received a grant to develop io_uring-like Ring
Buffer support at the system task level, as a first step towards ring buffer
communications between the application and the majority of system services. This
phase of the work finished up in September, as the last pieces were put in
place.
[…] In addition to implementing the Ring Buffer machinery for our system
services and drivers that can support it, an io_uring and liburing-like API for applications was completed and
demonstrated. There was also substantial work done on support crates, including
an async executor for drivers.
And there was some very exciting work on various performance improvements, to
allow much faster switching between applications and their system services. But
I will let the team tell you all the technical details.
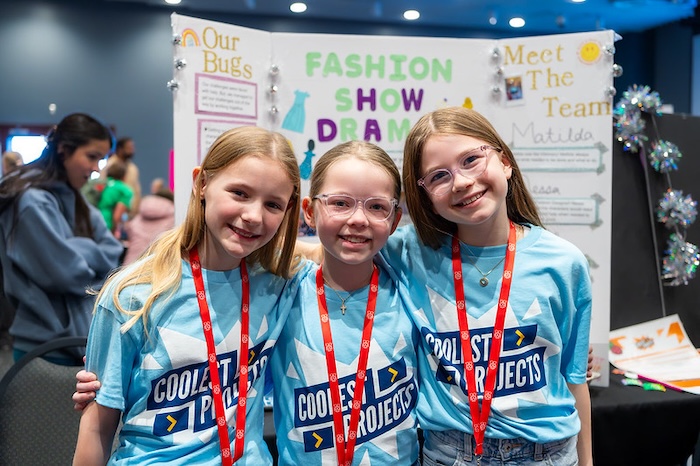
There are a few Coolest Projects events still to come in the Coolest Projects 2026 cycle, but we are already getting ready to kick off Coolest Projects 2027. Before we do, we’re taking a look back at some of the incredible things the young tech creators in the global Coolest Projects community have achieved this year, both through the online showcase and at in-person events around the world.
More than 15,000 young people from 40 countries shared over 4500 creations in the Coolest Projects online showcase. The Coolest Projects team hosted events in the UK, Ireland, India, and two locations across the US, while our partners brought creators together at in-person events in a further 11 countries, with events in Malaysia, South Africa and Argentina still to come.
With young people sharing their brilliant ideas, ambitious projects, and creativity with the world, 2026 has been a year to remember, and we can’t wait to see what comes next!
But don’t just take our word for it — hear from members of the Coolest Projects community about their experiences too.
From the community
For some, the events are about celebrating a shared passion for making with family and friends.
“I went to Coolest Projects last year with my cousins and thought it was cool, so I wanted to apply this year. I was very late applying so only had 3 days to create a project before the deadline. It was pretty intense! My highlight was being at the event with my cousin, Noah. It was great fun!” – Leo, creator, Coolest Projects Ireland
It’s not just creators who enjoy being part of the community. Mentors take away lasting impressions and a feeling of connection too.
“We usually avoid competitions because coding’s about curiosity, creativity, and sharing knowledge, not racing against each other. But Coolest Projects is completely different: it’s like one big party where everyone’s invited to share what they’ve made. We’re so grateful Project Code Cloud got to be part of it.” – Dannielle, Coolest Projects mentor, Australia
We are also very thankful to our VIP judges, who encourage and give feedback to creators both in the online showcase and at in-person events. Ben, a VIP judge for the online showcase, shared some powerful advice with creators:
“Keep building. Keep experimenting. Keep trying things. […] Always stay curious. Always try to stay learning. […] And the most important thing is it’s OK to fail. Trying new things is difficult and you’re always going to make mistakes, but that’s the best way to learn.” – Ben Powley, Senior Developer, Jagex
Catch up on the livestream to hear advice and feedback from all the VIP judges involved in the online showcase this year and check out their favourite projects.
Some more highlights from 2026
A judge who’s been in their shoes
Akari, a 16-year-old CoderDojo member from Japan who has showcased her own projects at Coolest Projects seven times, joined us as a VIP judge for the online showcase. We were delighted that young creators could hear a genuine peer voice on the panel, alongside industry judges, offering inspiration and encouragement.
This year’s Broadcom Coding with Commitment® recipient
The Broadcom Coding With Commitment® award is a special recognition for a creator who uses coding to support their community through a project that aligns with the United Nations Sustainable Development Goals. In this year’s online showcase, the award went to Egehan from Türkiye, for their Scratch project Viridia — Back to the World, an educational game that teaches players about water conservation. Egehan shared some thoughts about the challenges they faced while building it:
“Writing the code I used to create the 3D visuals for this game was a bit of a challenge for me. I would often dream about the mathematical calculations required for the code (which, to be honest, was quite interesting).” – Egehan
Partner events around the globe
With 14 partner events due to have taken place around the world by the end of 2026, more creators than ever before have been able to share their projects and connect with a like-minded community locally. Here are a few highlights from the events.
The first event of the year was Coolest Projects Belgium, which took place in March and was organised by CoderDojo Belgium. Ruhee, Global Partnerships Coordinator at the Raspberry Pi Foundation, who attended the event, was particularly impressed by Zeno and Lukas’s Orbitol 6 project, a three-axis robotic arm they’ve been developing for several years, with plans to take it from three axes to six in the future! She also highlighted Jack’s Moppentrappen, a joke-telling project that uses AI to replicate Jack’s voice, allowing it to tell jokes in French as well as English.
Coolest Projects Japan, organised by CoderDojo Japan, was also held in March and welcomed 79 entries, which you can explore here.
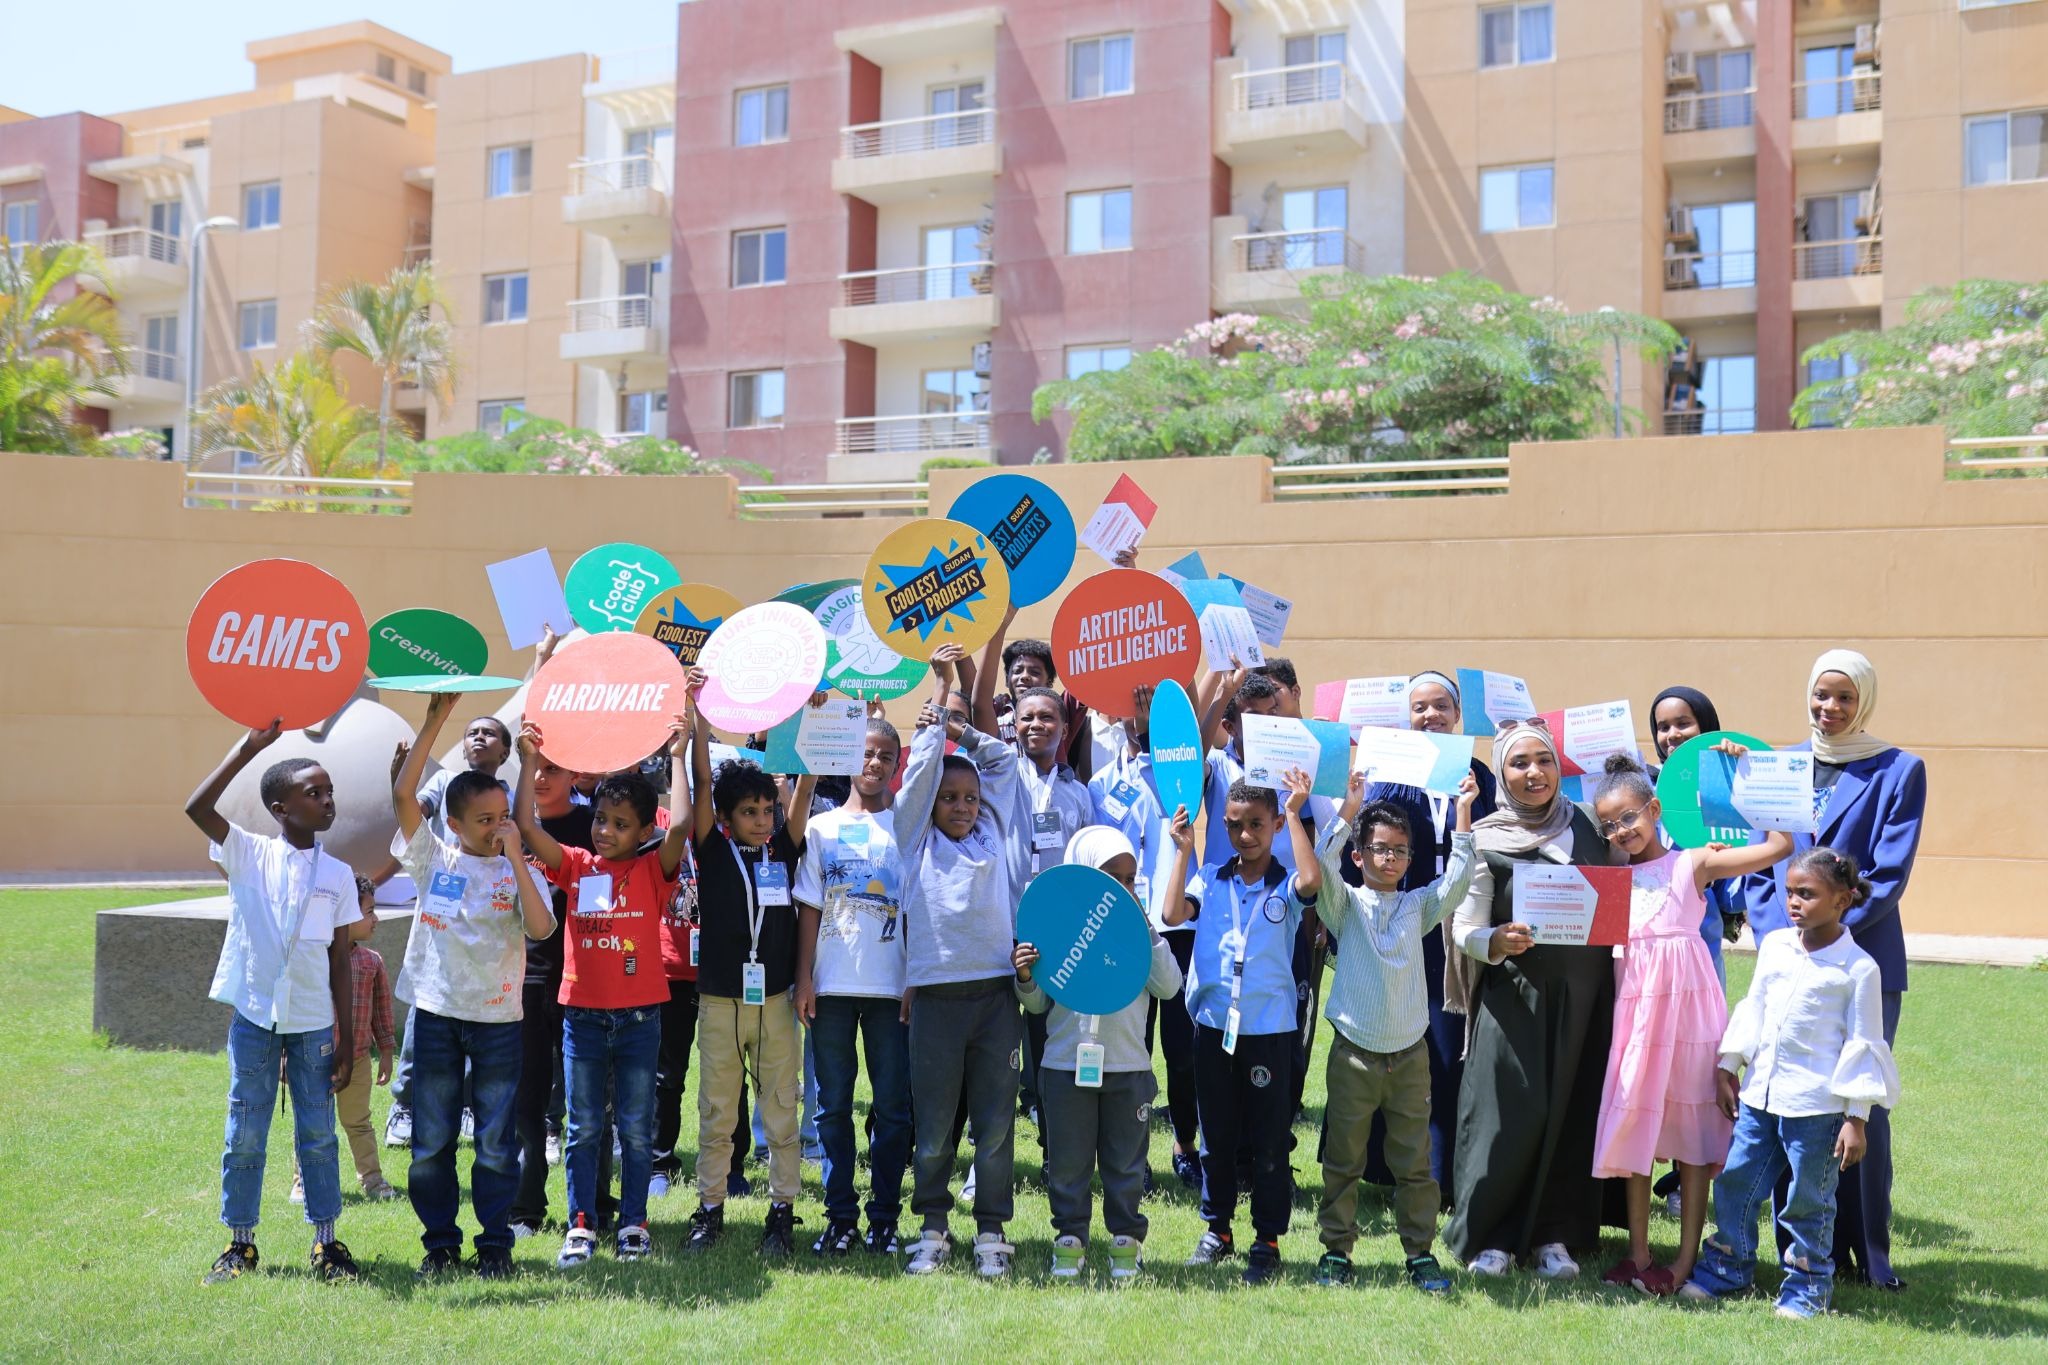
Coolest Projects Sudan, organised by Orientations Training Centre, ran for the second time this year. The event was held in Egypt and was designed to provide a safe and accessible space for young Sudanese people affected by displacement. Among the projects on display was an AI-based fruit freshness detector, built by 7-year-olds Khalid and Nour.
“This showcase reflects our belief that Sudan’s future depends on empowering young people to learn, create, and solve problems. We are committed to building the opportunities and platforms they need to shape a better future for Sudan.” – Abbdelmoneim M. Ahmed, CEO, Orientations Training Centre
Coolest Projects Sudan
Looking ahead to 2027
We are excited to share that the Coolest Projects 2027 online showcase will open for entries in January, and the Coolest Projects online showcase celebration will take place on 23 June.
We’ll also be running in-person Coolest Projects events in Ireland, the UK, India, the US, South Africa, and Kenya next year, with further in-person events due to be run by partners around the world. We will announce the full calendar of in-person events soon.
You can already save the date for:
Coolest Projects Belgium — 13 March 2027
Coolest Projects USA Minnesota — 17 April 2027
Coolest Projects Ireland — 24 April 2027 at Explorium, Dublin
Coolest Projects UK Bradford — 15 May 2027 at Life Centre, Bradford
Coolest Projects USA Georgia — 15 May 2027
Coolest Projects UK Cardiff — 22 May 2027 at Wales Millennium Centre, Cardiff
Coolest Projects global showcase celebration — 23 June 2027, online
If you would like to be first to hear news and dates for the 2027 online showcase and in-person events, sign up to our newsletter or follow the Coolest Projects social channels (find us on LinkedIn, Facebook, and Instagram).
The Lebanese International University (LIU) conducts applied networking research aimed at making professional-grade monitoring practices accessible in academic settings through its Department of Computer and Communication Engineering.
The department recently completed a research project that explored how Zabbix could be used to monitor a fully virtualized network environment, with the goal of offering a model that any academic or training lab could adopt.
The challenge
Networking education broadly relies on physical lab equipment (routers, switches) that is expensive to acquire, maintain, and scale, putting realistic, hands-on monitoring practice out of reach for many programs.
The research set out to test whether a simulated network environment could be monitored exactly as one would monitor production infrastructure – collecting live metrics, visualizing device health, and practicing remote management, while operating on a budget appropriate for an academic lab.
The solution
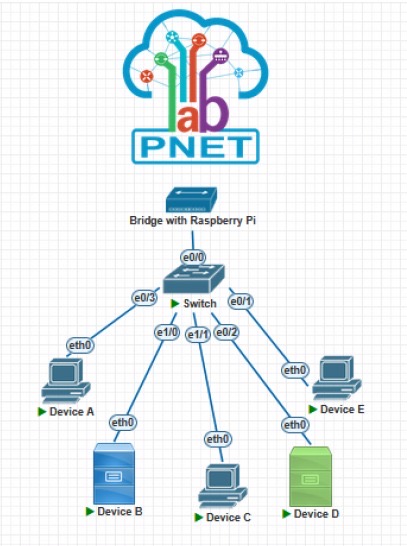
The team built a virtual network topology in PNETLab (routers, switches, and end devices using multi-vendor images) and connected it to a Zabbix server running on a low-cost Raspberry Pi 5.
Each virtual device was assigned IP addressing compatible with the Zabbix monitoring network, allowing Zabbix to poll the simulated devices via SNMP and ICMP exactly as it would poll physical infrastructure, which in turn allowed students to understand more how the infrastructure is behaving based on these polls.
This demonstrated that students and researchers can interact with a monitoring stack that behaves identically to an enterprise deployment, entirely on virtualized, reproducible lab infrastructure that costs a fraction of physical networking gear.
The results
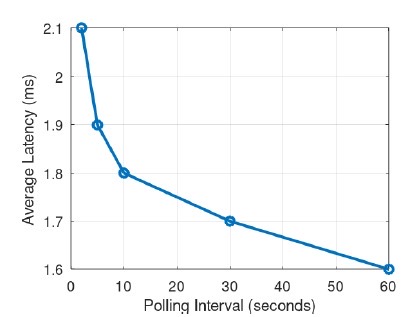
The integration proved that a virtual topology is indistinguishable from a physical one from Zabbix’s perspective – polling latency across 10 simulated devices averaged just 2.5ms, with the Raspberry Pi host staying under 15% CPU usage throughout testing.
The result was a reproducible, low-cost training model where networking and monitoring concepts can be taught hands-on, repeated across cohorts, and scaled by simply adding more virtual nodes in PNETLab rather than purchasing additional hardware – one that other academic institutions facing the same budget constraints could replicate directly.
In conclusion
By combining Zabbix, PNETLab, and a Raspberry Pi 5, the team at LIU created a low-cost, reproducible virtual lab that delivers hands-on monitoring experience without the expense of physical networking equipment.
With polling latency averaging just 2.5 ms across 10 simulated devices and CPU usage remaining below 15%, the results highlight the potential of virtualized environments for teaching real-world networking and monitoring skills.
Most importantly, this approach provides a practical, scalable model that other academic institutions can adopt to make hands-on IT infrastructure monitoring more accessible to the next generation of networking professionals.
For a more in-depth look at LIU’s project or to cite the published research, visit this website.
To find out more about what Zabbix can do for eduactional institutions, contact us.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.