Data Mesh at Grab Part II: The Foundational Tools behind Certification

Post Syndicated from Grab Tech original https://engineering.grab.com/data-mesh-2

Introduction

In Part I, we discussed why Grab is investing in a data mesh, referred to as the Signals Marketplace within Grab, as part of our evolving data culture. We also explained how data certification aids teams in reliably reusing data across different domains. However, cultural change doesn’t occur through principles alone; it happens when tools reshape people’s daily behaviors. Therefore, it is crucial for us to develop effective platforms that integrate these practices.

This follow-up focuses on these platforms that make certification work at Grab:

  • Hubble – the central metadata management platform with a built-in certification engine.
  • Genchi – the data quality observability platform.
  • Data Contract Registry – the central service for managing data contracts.

Together, these platforms turn data mesh principles into an operational system that scales across hundreds of thousands of datasets, streams, attributes, and metrics.

Hubble: The data discovery and governance layer

Hubble is Grab’s central metadata management platform and data catalog for all data assets, including datasets, dashboards, metrics, Machine learning (ML) models, and more. Built on top of the open‑source DataHub and heavily extended for Grab’s needs, it is the discovery and governance layer for the Signals Marketplace.
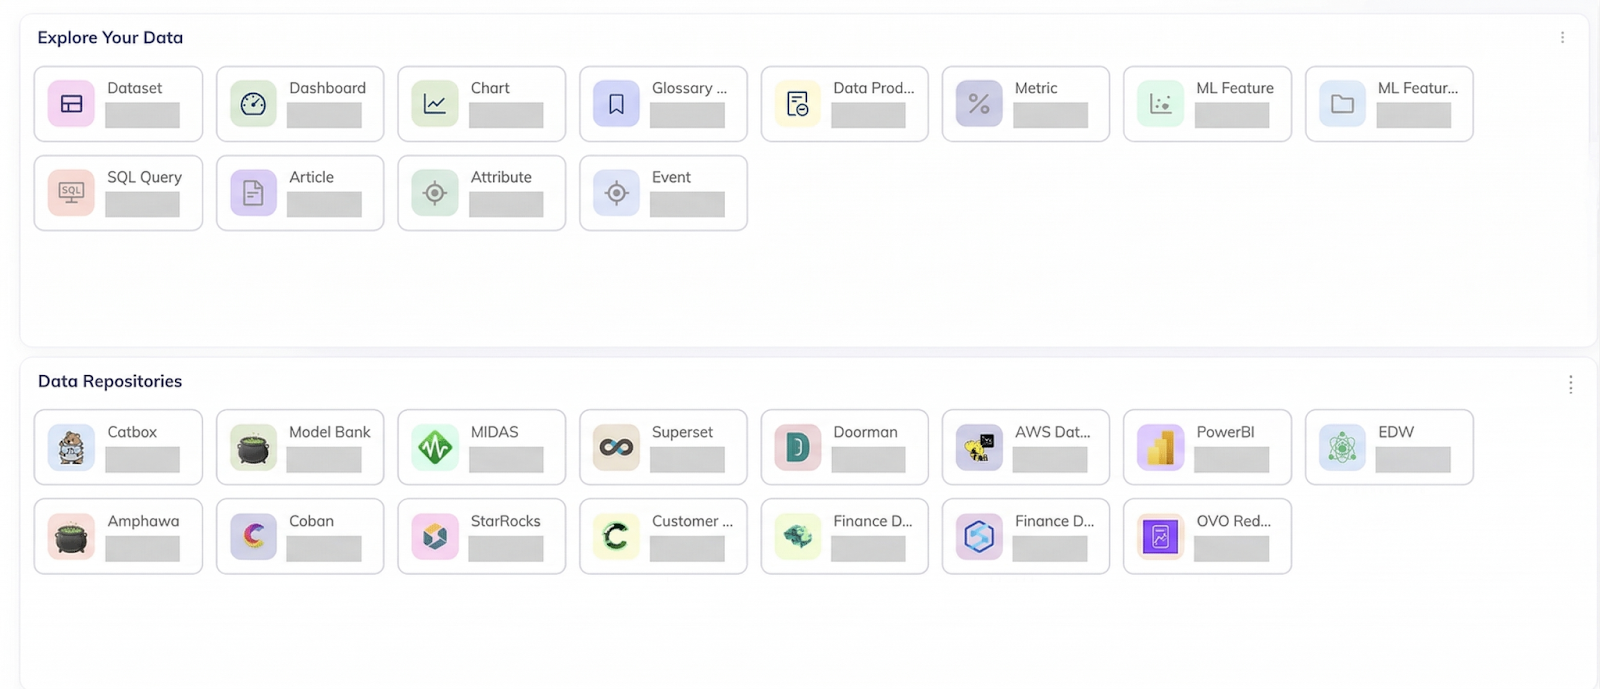
Figure 1. Hubble cataloging data assets across various data platforms in Grab.

What Hubble does for data mesh

For certification and data mesh, Hubble provides a few key capabilities:

  • Search and discovery: Data analysts/scientists, engineers, and product managers use Hubble to search the rich swath of data assets, then inspect schemas, documentation, lineage, and usage statistics in one place. This replaces back-channel questions and tribal knowledge with a single, self-serve catalog.
  • Ownership and domains: Every asset is tied to a domain and explicit technical and business owners. This enforces the domain ownership model that Signals Marketplace depends on. Producers are clearly accountable for the quality and lifecycle of the data products they publish.
  • Data contracts and documentation: Data contracts, classifications, and rich documentation live as structured metadata attached to each asset, not scattered across wikis and slide decks. Producers and consumers share the same source of truth when they ask questions like, “what does this table guarantee?”.
  • Lineage and impact analysis: Hubble provides table, column, and metric-level lineage so owners can see which teams and pipelines depend on their data before making breaking changes or deprecations. Instead of guessing, they can answer “what will I break?” with a single click.
  • Certification status: The familiar “Hubble green tick” turns trust into a first-class signal in the catalog. Assets that meet Grab’s certification criteria are clearly marked with a drill-down view of which criteria are satisfied (ownership, documentation, contracts, quality tests, upstream certification) and which are still missing.

From a consumer’s point of view, this collapses a lot of uncertainty into a simple workflow: search → filter to “certified” → pick the most suitable asset. They don’t need to reverse-engineer reliability from table names and hearsay.

Hubble’s system architecture

The open-source DataHub architecture is fundamentally event-driven and designed for high extensibility, moving away from the “passive” catalogs of the past, towards a “living” metadata graph. DataHub models everything as an Entity (e.g., a Dataset), composed of multiple Aspects (atomic versioned metadata like SchemaMetadata or Ownership), connected by Relationships (e.g., DownstreamOf).

Since introducing DataHub as Grab’s central data catalog in 2022, we’ve tailored it to Grab’s specific needs while continuously rebasing onto the latest open-source DataHub releases. This lets us adopt new capabilities from the community quickly, contribute improvements back, and evolve Hubble without forking away from the main project.

On top of the DataHub foundation, Hubble ingests metadata from Grab’s source platforms in two ways. Source systems either push changes as they happen, or Hubble periodically pulls metadata via Airflow jobs into the central metadata service that exposes GraphQL and REST APIs. Every change is then published to Kafka as metadata events (low-level change logs for indexers and audits, and higher-level semantic events for workflows), keeping Hubble’s search and lineage indices fresh and allowing downstream integrations like certification, deprecation notices, and governance automation to react to metadata changes in near real time.

This architecture is crucial for a data mesh because metadata evolves more rapidly than organizational changes. As domains change, tables are relocated, or pipelines are refactored, Hubble continuously updates, allowing certification to keep pace without the need for manual re-audits.
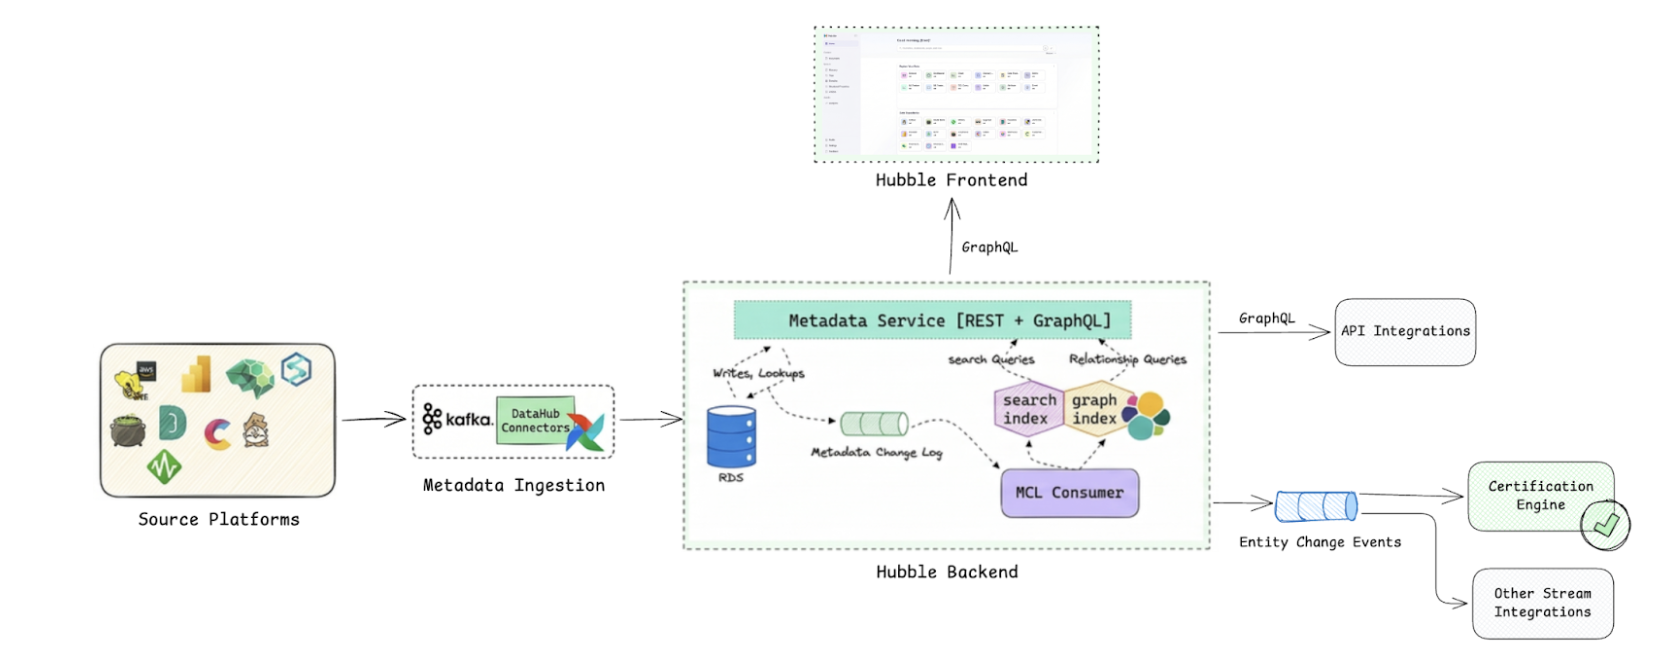
Figure 2. Hubble’s system architecture.

Computational certification via the certification engine on Hubble

A data asset’s certification state is not a manual label, it is computed by an event-driven certification engine built on the DataHub Actions framework. As source platforms for tables, streams, metrics, and user attributes push metadata into Hubble, every change becomes a metadata event. The engine subscribes to these events and re-evaluates the certification state of the data asset based on the predetermined certification criteria.

Conceptually, assets move between four states:

  • Uncertified: Never met all criteria.
  • Certified: Asset itself meets all required criteria.
  • CertifiedPlus: Stricter conditions than Certified, requiring both the asset and all of its upstreams to meet the criteria.
  • Revoked: Previously certified but now out of compliance.

The state diagram below captures how assets move between these states as metadata and upstream health change.
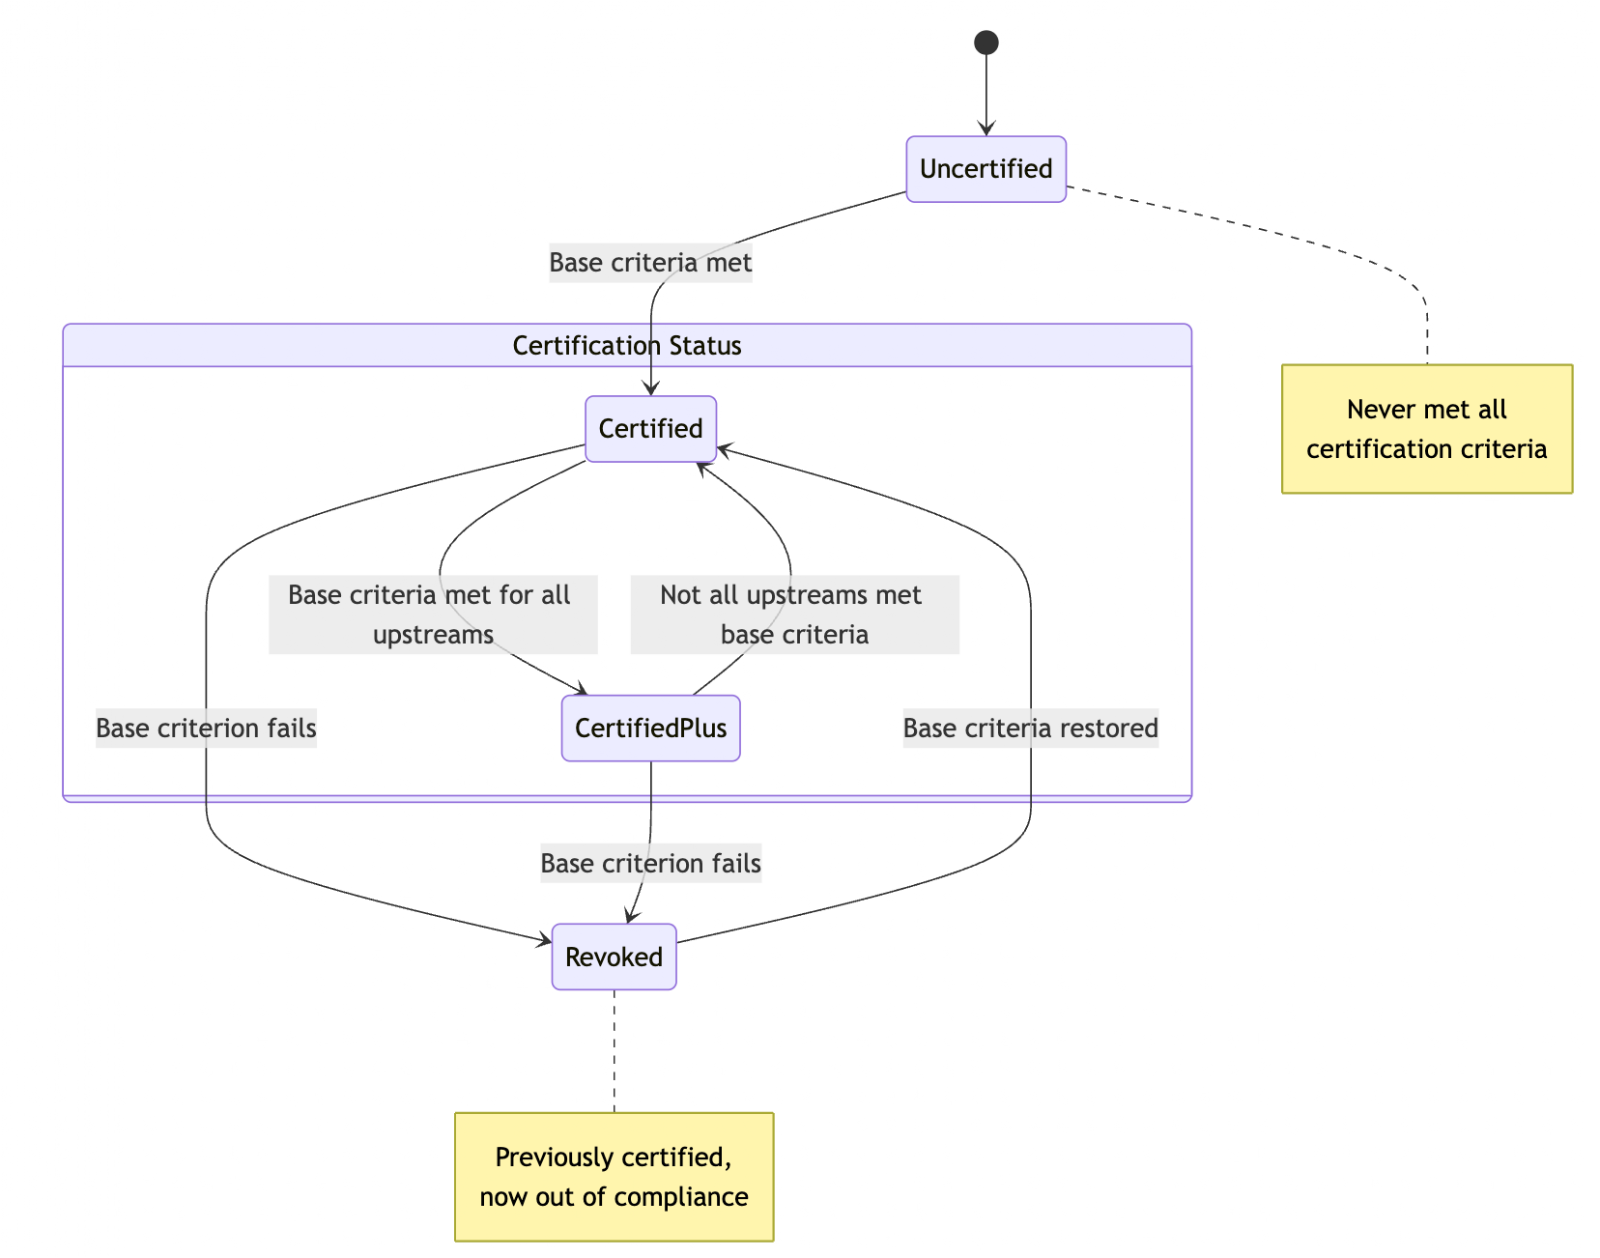
Figure 3. Certification state diagram.

While each asset type can add its own nuances (for example, metrics and attributes may also require explicit endorsement from business data owners), the core certification criteria are consistent:

  • Ownership and domain: Clear domain assignment plus accountable technical and business data owners.
  • Documentation and semantics: Table/metric documentation and, where relevant, column-level descriptions so consumers understand what the data means.
  • Lineage and upstream trust: For stronger levels like CertifiedPlus, upstream lineage must be present, and upstream assets must themselves be certified.
  • Contracts and runtime quality: Linked data contracts that spell out expectations, backed by required Genchi tests for freshness, volume/completeness, schema stability, and critical business checks.
  • Governance signals: No conflicting deprecation flags or policy violations (for example, missing required classifications on sensitive data).

If an asset satisfies the base criteria, the engine writes a certification aspect back into Hubble and surfaces it as a green tick; if the asset later falls out of compliance, certification is revoked, and downstream assets are re-evaluated as needed. This is because all certification changes are stored as time-series metadata and driven by events rather than a one-off checklist; certification becomes a continuous, metadata-driven process that keeps pace as the entity evolves.

Genchi: The data quality observability layer

Genchi is Grab’s in-house, self-service data quality observability platform. It allows teams to define and run data quality tests on their datasets, receive alerts when something goes wrong, and integrate those tests directly into data contracts so that issues are caught and contained before they impact downstream consumers.
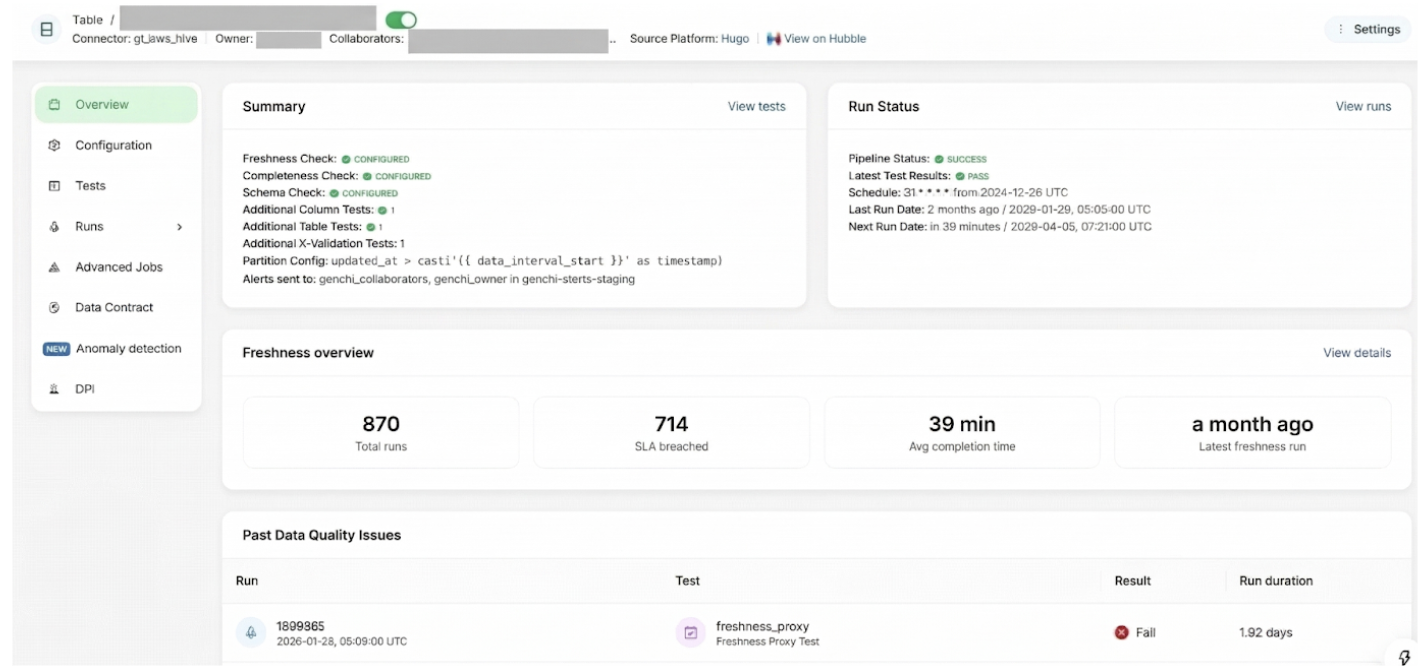
Figure 4. Genchi job configuration page, where dataset owners enroll a table and set up freshness, volume, schema, and other data quality tests for it.

What Genchi does for data mesh

In a data mesh, every domain is responsible for the quality of the data products it publishes. Genchi is the guardrail that makes that responsibility practical at scale. At its core, Genchi turns “good data” into clear, testable pillars that a data asset must satisfy:

  • Freshness and timeliness: Is the data recent enough to trust? Genchi runs data freshness and pipeline-freshness checks so owners know when today’s numbers are really “today’s” and can spot delayed loads before they hit dashboards or models.
  • Completeness and volume: Are we seeing all the records we expect? Volume and completeness tests compare current loads against historical baselines or source systems to flag partial backfills, silent drops, or suspicious spikes.
  • Structural stability (schema): Did the shape of the data change? Schema checks detect added/removed columns and type changes so that teams don’t discover breaking changes only after pipelines or reports start failing.
  • Semantic validity (values and business rules): Do the values themselves make sense? Column-level and X-Validation tests enforce constraints like uniqueness, ranges, patterns, cross-table reconciliations, and more advanced anomaly detection on row counts and null percentages.

Wrapped around these pillars is the operational layer:

  • Genchi runs these checks continuously (on schedule or on pipeline completion), emits real-time alerts, and helps teams drill into failing records and trends instead of debugging blind.
  • Its health signals flow into the catalog and incident tooling, so consumers see quality status alongside metadata and contract breaches are handled consistently.

The result is a mesh where domains publish data products with explicit, machine-enforced quality guarantees, and consumers can safely reuse them without a central team hand-holding every request.

Genchi’s system architecture

The Genchi system is designed to handle validation workflows triggered by user actions or automated schedules. It utilizes Temporal for reliable workflow orchestration and Kafka for event-driven data distribution to downstream consumers.
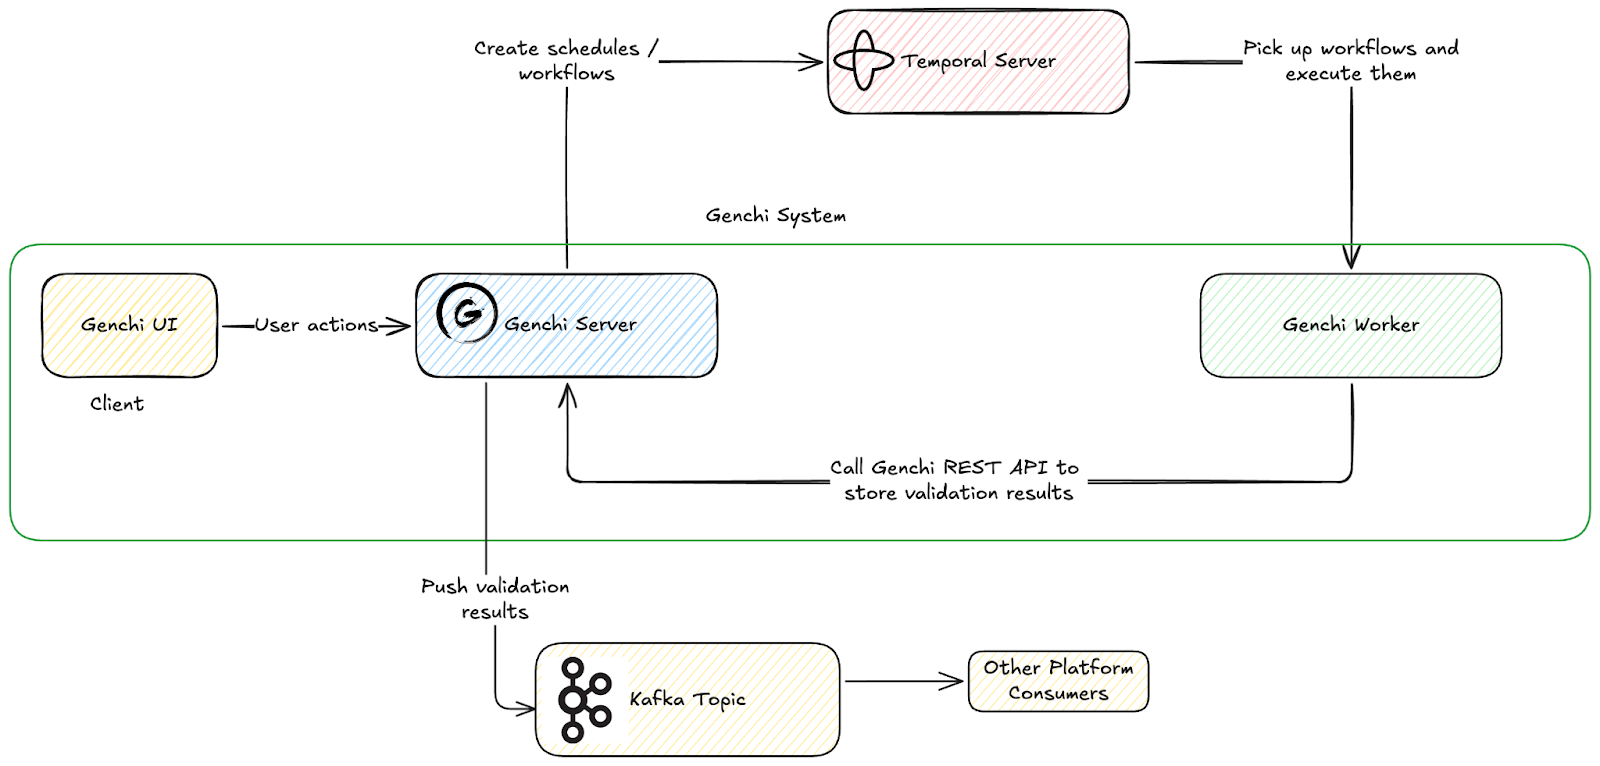
Figure 5. Genchi’s system architecture.

Triggering tests on pipeline completion with Sync with Pipeline (SWP)

Before SWP, Genchi tests lived on their own cron schedules, completely decoupled from the Airflow pipelines that actually produced the data. Teams had to manually copy pipeline crons into Genchi, juggle offset/lookback math to point at the “right” pipeline batch, and hope that nothing drifted over time. The result: misconfigured pipeline duration Service Level Agreement (SLA) checks, and tests sometimes running too early, too late, or against the wrong batch. This leads to noisy alerts and false-positive Data Production Issue (DPI).

To solve this, Genchi leans on Lighthouse, Grab’s pipeline execution and monitoring service. Lighthouse tracks when Airflow jobs start, finish, and which data interval they cover, and exposes that as structured execution events that the rest of the observability stack can consume.

SWP then flips Genchi from “best-effort cron alignment” to event-driven orchestration. Instead of guessing when a pipeline should have finished, Genchi listens to Lighthouse execution events. When a pipeline run is completed, Lighthouse emits an event with the run’s schedule and data interval; Genchi consumes that event, spins up an ad-hoc validation run aligned to that execution, and runs data-quality tests on the corresponding slice of data.

Pipeline-freshness is modeled as its own run type, separate from the data-quality tests that run on pipeline completion. Instead of inspecting rows, it is triggered asynchronously on the same schedule as the pipeline and tracks when each run actually completes in Lighthouse. This gives data producers an intuitive way to get alerted when a pipeline exceeds its expected runtime, and to review historical runtime behavior for any drift over time.

In practice, this makes test orchestration both simpler and more trustworthy. Users no longer need to think about crons or offsets for their data validation jobs. “Run after my pipeline finishes” becomes the default, with advanced overrides for custom schedules when needed. Misconfigured freshness tests and noisy DPIs drop, because Genchi is now anchored to real pipeline execution signals rather than approximations.
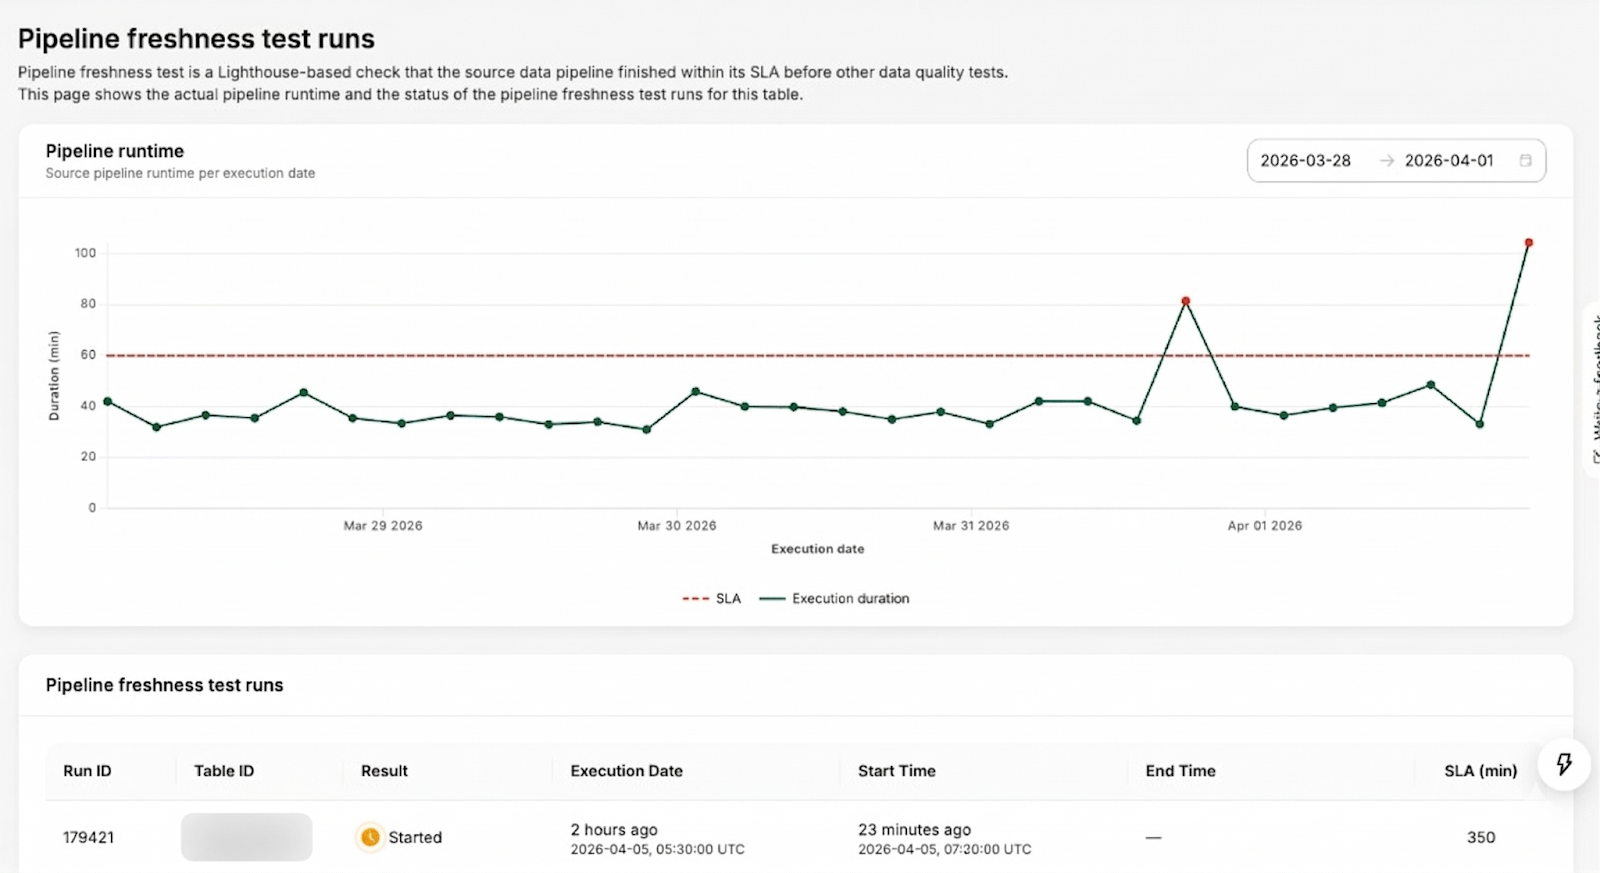
Figure 6. Genchi pipeline-freshness run page for a table, showing the historical runtime patterns and the SLA status.

Data Contract Registry: The producer–consumer agreement layer

At Grab, a data contract is the explicit, versioned agreement between a producer and its consumers that defines the data’s shape and semantics, the quality and availability guarantees around it, and the rules for how and for how long it may be used. The Data Contract Registry is the source of truth for these agreements, while Genchi and platform-specific observability stacks continuously verify that reality still matches what the contract promises.

What Data Contract Registry does for data mesh

Within Grab’s data mesh, the Data Contract Registry is the producer–consumer agreement layer: it centralizes contracts for key assets (data lake tables, Kafka streams, metrics) so expectations on shape, quality, SLAs, and lifecycle live in one canonical place instead of being scattered across individual platforms. That single source of truth underpins Hubble certification (only assets with valid contracts can be certified), gives Kinabalu (Grab’s central incident lifecycle orchestrator) the context it needs to open and route DPIs when checks fail, and lets Ouroboros (a table lifecycle management tool) interpret lifecycle clauses consistently.

This is important for a data mesh because it transforms the concept of “data as a product” from a mere slogan into an operational reality. Contracts provide domain teams with a clear and enforceable method to specify their guarantees, offering consumers a solid foundation for trust and data reuse across domains. Importantly, a contract is only valuable if its promises are verifiable and enforceable. Schema expectations, quality checks, and SLAs are all connected to concrete tests and health endpoints, enabling downstream platforms to automatically detect breaches and manage or mitigate breaking changes, rather than treating the contract as static documentation.

On top of storing contracts, the registry also manages contract changes. When a contract evolves, say a schema tweak, a new freshness SLA, or a planned deprecation, it identifies the right stakeholders (direct downstream owners, heavy query users, and, for critical assets, deeper dependencies) and pushes targeted Slack notifications. Producers get a structured way to roll out changes safely while consumers get timely, actionable signals instead of surprise breakages so that both enforcement and change management are baked into the mesh.

In addition to storing contracts, the registry also manages contract changes. When a contract evolves such as a schema adjustment, a new freshness SLA, or a planned deprecation, it identifies the appropriate stakeholder (direct downstream owners, heavy query users, and critical assets with deeper dependencies) and then sends targeted Slack notifications to these stakeholders. This process provides producers with a structured method to implement changes safely, while consumers receive timely and actionable alerts, preventing unexpected disruptions. As a result, both enforcement and change management are seamlessly integrated into the data mesh.

The data contract specification

Under the hood, a data contract in the registry is a JSON construct that follows the contract specification. Grab’s data contract specification is inspired by the public Data Contract Specification, but adapted to our environment so that contracts plug directly into our observability stack and automated incident management workflows.

Notably, we embed data health and test health URLs in the contract itself. Each data-quality rule points to a concrete health endpoint, so Kinabalu can determine contract breaches and create DPIs by calling those test health URLs, without hard-coding what “healthy” means. For example, a completeness test on the latest partition can be marked healthy only if the last N days are complete, not just because the most recent test run happened to pass. The data health URL at the contract root then lets Kinabalu fetch the overall diagnosis and decide who the DPI should be assigned to. More on this will be covered in Part III.

Here’s a simplified example of a contract for a data-lake table:

{
  "specification_version": 1,
  "asset_urn": "urn:li:dataset:(urn:li:dataPlatform:hive,genchi.validation_jobs,PROD)",
  "entity_type": "datalake_table",
  "health_url": "https://example-hugo.grab.com/assets/genchi.validation_jobs/health",
  "contract_details": {
    "contact": {
      "oncall_group": "oncall-genchi",
      "slack_channel": "ask-genchi"
    },
    "terms": {
      "usage": "Source of truth for all genchi validation jobs.",
      "limitations": "Not suitable for real-time use cases.",
      "notice_period_in_days": 14
    },
    "schema": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_schema_test/health",
        "uid": "fundamental_schema_test",
        "version": 1
      }

    ],
    "sla": {
      "freshness": [
        {
          "type": "genchi",
          "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_freshness_test/health",
          "uid": "fundamental_freshness_test",
          "version": 1
        }
      ],
      "lifecycle": null
    },
    "data_quality": [
      {
        "type": "genchi",
        "health_url": "https://example-genchi.grab.com/assets/genchi.validation_jobs/tests/fundamental_completeness_test/health",
        "uid": "fundamental_completeness_test",
        "version": 1
      }
    ]
  }
}

The contract in the registry only stores references to enforceable rules, which are an identifier and version, like the example above, rather than the full configuration body. This keeps contracts lightweight and tool-agnostic, while giving rule-enforcement tools (Genchi for data-quality tests, Ouroboros for table lifecycle) and Kinabalu a stable handle to resolve the actual rule definition in their own systems, without duplicating configuration or letting it drift across platforms.

Conclusion

By bringing Hubble, Genchi, and the Data Contract Registry together, we provide the foundational tools to build trust in certified data assets. Hubble enables discovery and establishes domains and ownership; the Data Contract Registry captures explicit expectations between producers and consumers; and Genchi continuously validates those promises with tests on freshness, volume, schema, and business rules. Hubble’s certification engine then evaluates these ownership, contract, and quality signals to decide whether an asset meets Grab’s standards and surfaces that as a visible certification state. As a result, consumers can confidently default to certified assets, usage converges on a smaller, better-governed pool of datasets, and certification becomes a mechanism that changes producer behavior and guides consumer choice. We saw this convergence in practice. In just one year since the Signals Marketplace campaign began in 2024, the number of P80 datasets (the most used tables that account for 80% of all queries) has dropped by over 58%.

This data foundation is especially important in an AI-first future for Grab. Certified streams, tables, metrics, and attributes give AI agents and automated analytics a default substrate they can rely on. With Hubble and Genchi, data producers have clear ownership, contracts, and observability. Data consumers can discover and trust certified assets without guesswork, and platform teams can measure and improve Signals Marketplace health over time (for example, queries on certified assets, lineage depth, and cost). Together, these capabilities turn “data mesh” from a slogan into an operational, AI-ready marketplace of reliable, reusable signals that power decisions across Grab.
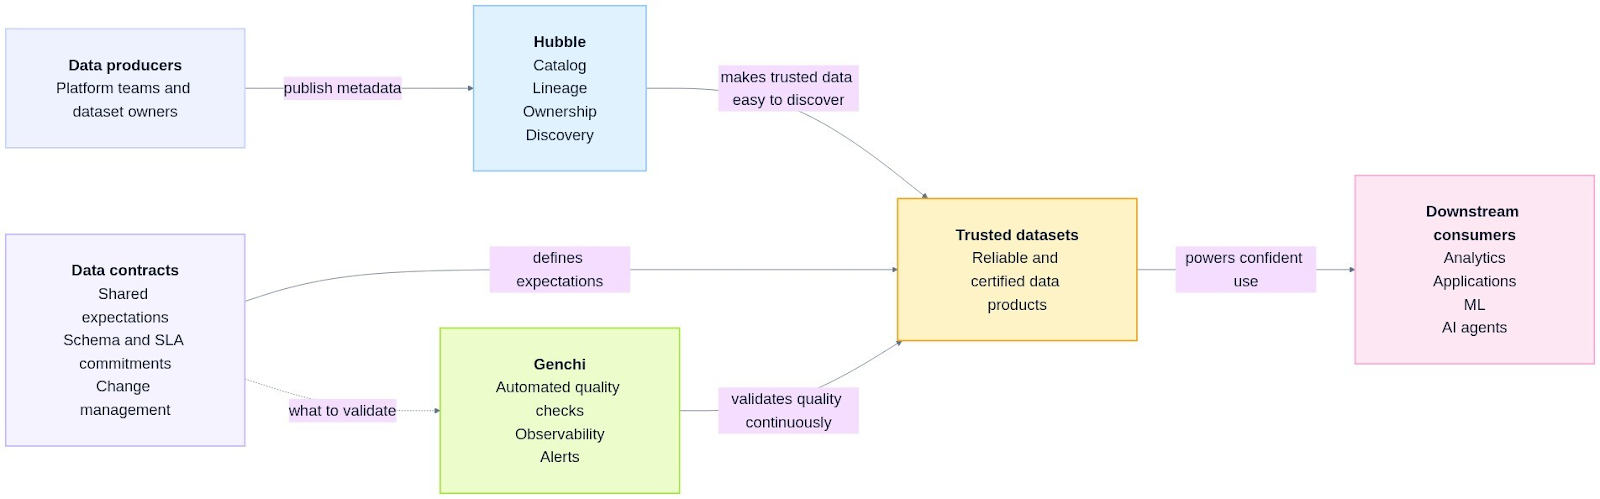
Figure 7. Building trust in certified data assets through discovery, contracts, and continuous validation.

What’s next

In the next blog, we’ll zoom into the DPI process itself with Kinabalu as the incident lifecycle orchestrator:

  • How Genchi test failures and data contract breaches turn into DPIs.
  • How DPI is assigned based on root causes and what sets the priority level.
  • The patterns we’ve seen in “noisy” vs actionable DPIs, and what we’ve changed in our platforms.
  • How we’re using automation and agents to reduce DPI toil and close the loop back into certification.

We’ll walk through concrete case studies showing how a single broken table moves from first failure, to diagnosis and fix, to updated contracts and a more resilient certified data asset.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors, serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
[$] LWN.net Weekly Edition for April 30, 2026

Post Syndicated from corbet original https://lwn.net/Articles/1069206/

Inside this week’s LWN.net Weekly Edition:

  • Front: Famfs; Python packaging council; Zig concurrency; pages and folios; Strawberry music manager; 7.1 merge window.
  • Briefs: GnuPG 2.5.19; Copy Fail; Plasma security; Fedora 44; Ubuntu 26.04; Niri 26.04; pip 26.1; RIP Seth Nickell; RIP Tomáš Kalibera; Quotes; …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

A security bug in AEAD sockets

Post Syndicated from daroc original https://lwn.net/Articles/1070454/

Security analysis firm Xint has disclosed a security bug in the Linux kernel
that allows for arbitrary 4-byte writes to the page cache, and which has been
present since 2017.
The vulnerability has

been fixed
in mainline kernels. A
proof-of-concept script
demonstrates how to use the flaw to corrupt a setuid
binary, which works on
multiple distributions, by requesting an AEAD-encrypted socket from user space
and splicing a particular payload into it.
A supplemental blog
post
gives more details about the discovery and remediation.

A core primitive underlying this bug is splice(): it transfers data between file
descriptors and pipes without copying, passing page cache pages by reference.
When a user splices a file into a pipe and then into an AF_ALG socket, the
socket’s input scatterlist holds direct references to the kernel’s cached pages
of that file. The pages are not duplicated; the scatterlist entries point at the
same physical pages that back every read(), mmap(), and
execve() of that file.

Five Things we Took Away from Gartner SRM Sydney 2026

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/it-5-things-gartner-srm-sydney-2026

At this year’s Gartner Security and Risk Management Summit in Sydney, Rapid7 CISO Brian Castagna joined industry CISO Nigel Hedges for a fireside chat on the decisions security leaders are actually making right now. They discussed the real decisions being made right now about budgets, burnout, AI, and perspective on consolidation.

The conversation reinforced what we see across many organizations: SecOps is very much focused on protecting business resilience, enabling confident decisions by senior security leaders, and building programs that scale across people, platforms, and emerging technology. Let’s now take a look at some of the main highlights from this year’s Summit.

The business case for SecOps has shifted and boards are listening

The ‘invest in security or get breached’ pitch has run its course. Boards have heard it too many times; plus, it frames security as a cost center that only proves its value when something goes wrong.

We’re seeing it being replaced by a resilience narrative. In most incidents, the biggest business impact is operational disruption. Hours or days of downtime create immediate revenue loss, reputational damage, and perhaps worse still for some, regulatory exposure. CISOs who can connect their programs to that reality – translating incident data into business availability and financial risk – find it significantly easier to justify spend and shape investment decisions.

That shift in dynamic changes what gets measured and prioritized as well as how security leaders communicate upward to the board. Threat intelligence and kill chains still matter inside the SOC, but the ability to translate that to a clear risk narrative is fast becoming a leadership requirement in its own right.

Platform consolidation is growing, but it’s not binary

The platform-vs-best-of-breed debate was notably pragmatic. The real question is how to strike the right balance: Consolidate where it improves efficiency and visibility, retain point solutions where they materially reduce a specific risk.

On the ground, budget pressure has accelerated this. Fewer vendors, more integrated telemetry, and clearer operational ownership help make spend more defensible. The discussion framed consolidation through the lens of ‘control planes’ (endpoint, gateway, network), with shared telemetry as the connective layer.

A real-world example grounded the conversation: Build a global security program for a 5,000-person organization across 40 countries on a $3 million budget, using a selective mix of MDR, PAM, EPM, and targeted point solutions only where necessary. Throughout, the operating principle was simple in that every security investment needs to answer one question: What risk does this reduce, and importantly, what business outcome does it protect?

People remain the most difficult element of SecOps

Technology and process can be engineered, but people? They’re much harder. That was one of the most practical observations from the session, and it resonated with every security leader in the room.

The challenge goes beyond hiring technical talent to ensure organizations are building teams with the right mix of communication skills, cognitive diversity, motivation, and endurance. A common gap seen in the SOC is that many teams are strong technically but few can articulate risk effectively to executives. That matters because the value of SecOps increasingly depends on how well teams connect activity to impact.

At the same time, burnout remains a structural issue. When experienced analysts leave, institutional knowledge leaves with them. And no tool can replace that. For leaders, this reinforces the point that people strategy is core to the overall security strategy.

AI in SecOps is getting very real, and very practical

After a long hype cycle, the AI conversation is now far more grounded. The most credible use cases in SecOps are about helping teams manage volume, reduce noise, and move faster with better context.

The examples discussed in the session were telling: alert-assisted triage, natural-language log querying, incident summarisation, first-draft executive communications, and eventually more automated investigation workflows. The framing that landed best was AI as a ‘sidearm partner’; a force multiplier for experienced practitioners, rather than a substitute for judgment.

That distinction matters as human judgment is essential. But AI is becoming increasingly valuable for understaffed teams trying to scale operations and preserve the institutional knowledge that walks out the door when analysts move on.

Governing agentic AI begins with foundations you should already have

As the discussion turned to agentic AI, the focus centred on how more autonomous AI systems do introduce new governance questions, but many of the relevant controls already exist within mature security programs. Segmentation, least privilege, access management, and strong architectural boundaries remain the core defenses.

One analogy stuck: Just as graphite rods slow a nuclear chain reaction, controls like network segmentation and access boundaries can contain and constrain agentic behavior. The organizations best positioned for AI governance are often the ones that have already invested in zero trust principles and sound identity controls.

That reframes the conversation. AI governance isn’t a separate discipline,  it’s the extension of existing security foundations into how AI systems behave, access data, and operate within defined boundaries.

What this means for the road ahead

If there was a unifying message, it was that the modern SecOps mandate is bigger than prevention. The industry has, to some extent, over-rotated on stopping threats and under-invested in resilience. 

Security leaders require programs that communicate risk in business terms, make smart technology trade-offs, support their people, and adopt AI in ways that are practical and governable. The organizations that get this right will be the ones building strong foundations and using the right mix of platform, process, and intelligence to move faster and more confidently. 
Rapid7 is committed to being a partner to organizations looking to gain that confidence. Our exposure-informed MDR service empowers teams to adopt a more preemptive security posture by rapidly identifying high-impact exposures that could be imminent breach targets. Teams can also leverage expanded capabilities in data security posture management (DSPM) and compliance to help fortify assessment, prioritization, and response capabilities so they can further preempt attacks across the modern attack surface.

CVE-2026-41940: cPanel & WHM Authentication Bypass

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-cve-2026-41940-cpanel-whm-authentication-bypass

Overview

On April 28, 2026, cPanel issued a security update to fix a critical vulnerability affecting the cPanel & WHM and WP Squared products. In the cPanel release notes, the bug was described as “an issue with session loading and saving.” CVE-2026-41940, the identifier subsequently assigned on April 29, 2026, has a CVSS score of 9.8 and allows unauthenticated remote attackers to bypass authentication and gain unauthorized administrative access to the affected systems. First-party cPanel & WHM and WP Squared vendor advisories are available.

cPanel & WHM is web hosting control panel software used to manage websites and servers. WHM provides root-level administration, while cPanel acts as the user-facing interface. Successful exploitation of CVE-2026-41940 grants an attacker control over the cPanel host system, its configurations and databases, and websites it manages. A naive Shodan query for potential targets returns approximately 1.5 million cPanel instances exposed to the internet that may be vulnerable.

A managed cPanel host, KnownHost, stated that CVE-2026-41940 is actively being exploited in the wild, with speculation of targeted zero-day exploitation happening as early as February 23, 2026, prior to the vulnerability’s public disclosure. Security firm watchTowr has published a technical analysis and proof-of-concept exploit for CVE-2026-41940. As such, widespread exploitation in the wild is expected to be imminent.

Technical overview

Systems exposing the affected web service software are vulnerable by default.

As of April 29, 2026, a technical analysis and proof-of-concept exploit have been published by security firm watchTowr. CVE-2026-41940 is an authentication bypass caused by a Carriage Return Line Feed (CRLF) injection in the login and session loading processes of cPanel & WHM.

Before authentication occurs, `cpsrvd` (the cPanel service daemon) writes a new session file to the disk. The vulnerability allows an attacker to manipulate the `whostmgrsession` cookie by omitting an expected segment of the cookie value, avoiding the encryption process typically applied to an attacker-provided value. Attackers can inject raw `\r\n` characters via a malicious basic authorization header, and the system subsequently writes the session file without sanitizing the data. As a result, the attacker can insert arbitrary properties, such as `user=root`, into their session file. After triggering a reload of the session from the file, the attacker establishes administrator-level access for their token.

Mitigation guidance

Organizations running on-premise instances of cPanel & WHM or WP Squared should prioritize upgrading to a fixed version on an emergency basis. Some hosting providers have opted to temporarily institute workaround TCP port blocks for cPanel & WHM web services on ports 2083 and 2087. However, defenders are strongly advised to patch, rather than implement workarounds.

Affected Software:

  • cPanel & WHM 11.110.0 versions prior to fixed version 11.110.0.97

  • cPanel & WHM 11.118.0 versions prior to fixed version 11.118.0.63

  • cPanel & WHM 11.126.0 versions prior to fixed version 11.126.0.54

  • cPanel & WHM 11.132.0 versions prior to fixed version 11.132.0.29

  • cPanel & WHM 11.134.0 versions prior to fixed version 11.134.0.20

  • cPanel & WHM 11.136.0 versions prior to fixed version 11.136.0.5

  • WP Squared 11.136.1 versions prior to fixed version 11.136.1.7

Please read the vendor advisory for the latest guidance.

Exposure Command, InsightVM, and Nexpose

Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-41940 with authenticated vulnerability checks expected to be available in the April 30, 2026 content release.

Updates

April 29, 2026: Initial publication.

Designing trust and safety into Amazon Bedrock powered applications

Post Syndicated from Victor Lungu original https://aws.amazon.com/blogs/security/designing-trust-and-safety-into-amazon-bedrock-powered-applications/

Generative AI brings promising innovation, transforming how individuals and organizations approach everything from customer service to content creation and more. As AI continues to expand its capabilities, organizations are increasingly focused on how they can integrate the responsible AI concepts into the development lifecycle of their AI applications.

Research from Accenture and Amazon Web Services (AWS) reveals compelling evidence for the business value of responsible AI practices, both internally within their organizations and externally to their users. Organizations that communicate a mature approach to responsible AI see an 82% improvement in employee trust in AI adoption, which directly leads to increased innovation. Additionally, companies that offer responsible AI-enabled products and services experience a 25% increase in customer loyalty and satisfaction.

Understanding the core dimensions of responsible AI

AWS identifies these key dimensions that form the backbone of responsible AI implementation:

  • Safety focuses on preventing harmful system output and misuse. This dimension focuses on steering AI systems to prioritize user and system safety.
  • Controllability focuses on mechanisms that monitor and steer AI system behavior. This dimension refers to the ability to manage, guide, and constrain AI systems to operate within specific parameters.
  • Fairness considers the impacts of AI on different groups of users.
  • Explainability focuses on understanding and evaluating system outputs.
  • Security and privacy focuses on making sure that data and models are appropriately obtained, used, and protected.
  • Veracity and robustness focuses on achieving correct system outputs, even with unexpected or adversarial inputs.
  • Governance makes sure that development, deployment, and management of AI systems align with ethical standards, legal requirements, and societal values.
  • Transparency focuses on understanding how AI systems make decisions, why the systems produce specific results, and what data the systems use.

It’s a best practice to review and apply all these dimensions to your AI implementation. For more information, see Considerations for addressing the core dimensions of responsible AI for Amazon Bedrock applications.

The responsible AI lifecycle

When you implement AI systems, you should build safety into every phase of the AWS responsible AI lifecycle. The responsible AI lifecycle consists of the following three phases, each with distinct responsibility considerations for the safety dimension:

  1. In the design and development phases, thoroughly evaluate potential safety risks. Understand what you want your AI application to do, what you don’t want it to do, and what you want to prevent it from doing. You should build safety guardrails into your systems from the beginning and make sure that your development teams understand the capabilities and limits of your AI application.
  2. In the deployment phase, theory meets reality. During this phase, you should implement robust safety measures through multiple layers, from comprehensive user training to proactive monitoring and review processes. Every application, product, and feature must include clear safety protocols and user guidelines. You must think beyond the launch of an application and consider how to launch a holistic safety framework. This framework—which can contain steps such as red team testing—must protect your brand, users, and stakeholders.
  3. In the operations phase, it’s important to maintain vigilance. Safety, like security, isn’t something you set up once and then ignore. Safety requires continuous monitoring and adaptation. To catch potential safety issues early, you can implement real-time feedback mechanisms to conduct regular performance evaluations. You can also continuously monitor for shifts in how your application is used, or functions that could compromise safety. Because safety considerations and risks evolve as technology evolves, it’s crucial to understand that adjustments are necessary over time.

For more information, see the Responsible use of AI guide.

Abuse detection

Foundation models in Amazon Bedrock are inherently designed with safety mechanisms to prevent harmful outputs. However, you can implement additional input safety systems in production environments to provide critical early detection capabilities to identify problematic content, users, or patterns.

Note: Amazon Bedrock might implement automated abuse detection mechanisms to identify potential violations of the AWS Acceptable Use Policy (AUP) and Service Terms, including the Responsible AI Policy or a third-party model provider’s AUP.

See the Amazon Bedrock abuse detection document for more information.

AI abuse prevention tools and techniques

To maintain trust in your AI services, preventative action is key, while also efficiently planning and managing development resources. Introduce observability and safety guardrails early in development to support long-term scalability and help identify potential issues before they affect your users. To begin this process, thoroughly scope your AI use case with the following actions:

  • Understand your users
  • Anticipate potential misuse scenarios
  • Define your risk tolerance

This scope guides your development of a precise safety framework that addresses the specific risks of your AI implementation while you maintain expected performance. For this scope, you can use AWS specialized tools designed specifically to monitor and protect Amazon Bedrock applications.

Using CloudWatch to monitor Amazon Bedrock

Amazon CloudWatch provides essential visibility into AI system behavior and performance. When you configure comprehensive logging, you can capture important information across user segments and interaction types, such as the following:

  • Request volumes
  • Response latencies
  • Rejection rates
  • Content filtering triggers

You can use this information to identify potential abuse patterns or unexpected behaviors before they affect operations. CloudWatch dashboards visualize metrics according to monitoring priorities, and automated alerts provide prompt notification when you exceed thresholds. This infrastructure transforms interaction data into actionable insights and supports continuous safety improvement.

Note: By default, Amazon Bedrock logging is turned off. You must turn on logging for your application. To configure this, contact your account manager.

Using Amazon Bedrock Guardrails to customize safeguards

Amazon Bedrock Guardrails offers configurable protection mechanisms tailored to specific risk profiles and content policies. You can customize Bedrock Guardrails to match your application requirements, such as:

  • Define domain-relevant undesirable topics
  • Configure appropriate content filtering thresholds
  • Configure sensitive information detection and redaction parameters aligned with data policies

Additionally, you can configure controls that prioritize accuracy and prevent hallucinations while maintaining creative flexibility based on your application needs. When you thoughtfully configure Guardrails, you can balance performance and safety according to your specific use case requirements and risk factors.

The abuse response process

As AI safety evolves and new risks emerge, abuse might still occur even if you implement safety mechanisms. If you receive an abuse report from the AWS Trust & Safety team, then complete the following steps to help effectively address the issue:

  1. Acknowledge receipt: Acknowledge the receipt of the abuse report within 24 hours. If your team is still conducting their investigation, then inform AWS that the investigation is ongoing. Provide the number of days expected to complete the investigation.
  2. Investigate the issue: Thoroughly investigate the issue, including examining the logs (if enabled), reviewing Amazon Bedrock inputs, and checking for unauthorized access. While AWS abuse reports include a small sample of prompt IDs for you to investigate, investigate usage of your Amazon Bedrock application. Check for patterns to see if there’s a systemic issue that’s leading to abuse.
  3. Take appropriate action: If appropriate, take action to implement fixes, update safeguards, address violating users, or redesign features. Consider if you need systemic or root-cause fixes, rather than addressing one abusive end user. An abuse incident by one user could indicate vulnerabilities in your safety mechanisms that can lead to continuous abuse.
  4. Report back to AWS Trust & Safety: Following your investigation and implementation of fixes, provide an update to AWS Trust & Safety on your findings and remediation steps. Be transparent about what happened and how you addressed the issue. If you think that no violation occurred, then provide context on how you came to this conclusion. Include examples of the prompts and your business use case where possible.

Conclusion

To learn more about safety and responsible AI development, explore AWS resources, including the Responsible AI portal and machine learning best practices documentation. These resources provide additional tools and frameworks to build safe, effective AI systems that drive innovation and maintain safety standards.

Victor Lungu
Victor Lungu

Victor is a Trust & Safety AI Abuse Specialist at AWS, based in Dublin. Victor works across a broad range of AI safety domains including content safety and emerging AI risks

[$] Python packaging council approved

Post Syndicated from jake original https://lwn.net/Articles/1068704/

The Python packaging world now has a formal
governance council, of the form described in PEP 772 (“Packaging
Council governance process”), which was approved
by the steering council
on April 16. It has been over a year
since the PEP was first proposed in February 2025 and it has undergone
lengthy discussions in multiple postings to the Python discussion forum. The
packaging council will have “broad authority over packaging standards,
tools, and implementations
“; it will consist of five members who will
be elected in a vote that is likely to come in June—after PyCon US 2026 is held mid-May.

Security review of Plasma Login Manager (SUSE Security Team Blog)

Post Syndicated from jzb original https://lwn.net/Articles/1070434/

SUSE’s Security Team has published a detailed
blog post
on their recent review of the Plasma
Login Manager
version 6.6.2,
which was forked from the SDDM display
manager
.

While most of the code remains the
same
, the new upstream added a privileged
D-Bus helper
called
plasmaloginauthhelper, which suffers from defense-in-depth
security issues
.

[…] Based on the high severity of the defense-in-depth issues
shown in this report, our assessment is that there is effectively no
separation between root and the plasmalogin service user account.

At this time there is no bugfix available by upstream, but a
security fix is planned for the next Plasma release on May 12. We have
not been involved in upstream’s bugfix process so far and have no
knowledge about the approach that will be taken to address the issues
from this report.

Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1070428/

Security updates have been issued by AlmaLinux (firefox, gdk-pixbuf2, java-17-openjdk, libxml2, python3, python3.11, python3.12, sudo, and webkit2gtk3), Debian (dnsdist, node-tar, pdns, pdns-recursor, and policykit-1), Fedora (chromium, edk2, and vim), Oracle (firefox, gdk-pixbuf2, go-toolset:rhel8, libpng12, LibRaw, libxml2, python, python3, python3.11, python3.12, python3.12-wheel, vim, webkit2gtk3, xorg-x11-server, xorg-x11-server-Xwayland, yggdrasil, and yggdrasil-worker-package-manager), Red Hat (container-tools:rhel8, delve, git-lfs, go-rpm-macros, grafana, grafana-pcp, osbuild-composer, and rhc), SUSE (bouncycastle, clamav, container-suseconnect, dovecot22, erlang, firefox, fontforge, freerdp2, ghostscript, giflib, gnome-remote-desktop, go1.25, go1.26, google-guest-agent, haproxy, ignition, ImageMagick, kernel, libcap, libpng16, libraw, librsvg, mariadb, openexr, pocketbase, protobuf, python-Pillow, python-requests, qemu, rust1.94, sudo, tomcat, tomcat10, tomcat11, webkit2gtk3, and xen), and Ubuntu (dotnet10, dovecot, linux-nvidia-lowlatency, node-follow-redirects, openssh, packagekit, python-cryptography, python-tornado, ruby-rack-session, ujson, and wheel).

Experts on Experts: The 2026 Threat Landscape is Moving Faster than Defenders Expect

Post Syndicated from Craig Adams original https://www.rapid7.com/blog/post/it-security-experts-2026-threat-landscape-moving-faster-than-defenders

This week on Experts on Experts, I’m joined by Christiaan Beek, Rapid7’s VP of Threat Analytics, to talk through what we’re seeing in the 2026 threat landscape and how it connects to recent research coming out of Rapid7 Labs.

We start with the report, but quickly move into what’s already playing out in active campaigns. What stands out is not a change in attacker technique, but the pace. Weak credentials, missing MFA, exposed services, and unpatched systems still drive most intrusions. What has changed is how quickly those conditions are identified and exploited, and that shift is forcing security teams to rethink how they prioritize and respond.

The window to act is disappearing

One of the clearest themes in the conversation is timing. The issue is no longer how many vulnerabilities exist, but how quickly they are being used. The gap between disclosure and exploitation has narrowed to a matter of days in many cases, which removes the buffer teams used to rely on.

At the same time, most intrusions still begin with familiar conditions. Identity and access remain consistent weaknesses, with missing MFA and exposed remote access continuing to provide reliable entry points. What has changed is how those weaknesses are used. Access is now packaged and sold through a broader ecosystem, which increases both the speed and scale of attacks.

Access, persistence, and trusted systems

We also look at how attacker behaviour is evolving beyond initial access. In some environments, the goal is no longer immediate disruption but long-term presence. That changes how teams should think about detection, because finding activity is only the starting point. Understanding how long access has existed and what has already happened becomes just as important.

At the same time, attacks are concentrating inside systems organizations rely on every day. Identity platforms, cloud environments, and collaboration tools are all becoming key targets. The challenge is that activity in these systems often looks legitimate, which makes it harder to distinguish between normal behaviour and something that requires investigation.

AI is accelerating what already works

AI is part of this shift, but not because it introduces entirely new attack paths. What it does is make existing techniques faster and easier to scale, particularly in areas like social engineering and reconnaissance. Attackers can generate and adapt campaigns quickly, while defenders are dealing with increasing volumes of data.

That creates a simple but important shift. Security teams are not falling behind because they lack tools, but because the timing of attacks has changed and their processes have not kept up. The focus now is on understanding exposure earlier, prioritizing what matters, and preparing actions in advance.

Watch the full episode below to hear Christiaan’s perspective on how these trends are evolving and what they mean for security leaders heading into 2026.

⠀

Яна Кършийска: Библиотеките са храм на комуникацията

Post Syndicated from Ина Иванова original https://www.toest.bg/yana-kurshiyska-bibliotekite-sa-hram-na-komunikatsiyata/

Яна Кършийска: Библиотеките са храм на комуникацията

Представете си, че страдате от безсъние, налага се да пишете научна работа или искате късно нощем да се усамотите на светло и тихо. Има ли във вашия град обществено място, на което да бъдете едновременно защитени и в усамотение?

Извън България не е необичайно библиотеките да функционират като многофункционални обществени центрове, които комбинират културни, образователни и обществени роли. Те вече са не просто места за книги, а активни хъбове, които могат да се използват от различни общности. Точно така функционира Регионална библиотека „Пейо Яворов“ в Бургас.

Намира се на мястото на някогашната Немска болница и е единствената нова сграда, строена в последните десетилетия у нас и нарочно предназначена за нуждите на библиотека и културно-образователен център – около 6000 квадратни метра с читални, интерактивни зали и конферентна зала, галерия и впечатляващ архив, магичен път с модули, свързани с обучението по науки и устойчива околна среда, вътрешен двор, подземен паркинг, книжарница и детски център с добавена реалност. Работи без почивен ден, от понеделник до неделя, от 8 до 23 часа, а в летния сезон и 24/7. Горе-долу по всяко време на денонощието там може да бъде срещната и Яна Кършийска, директорка на институцията.

Яна работи като администратор, но живее с размаха на творец, обладан от идея. Като дете мечтае да стане ветеринарна лекарка заради любовта си към животните, през 90-те обаче е приета с висок успех в тогавашния Държавен библиотекарски институт. По това време установява, че библиотекознанието е сериозна наука. Да си библиотекар е предизвикателство – имаш достъп до всички полета на познанието, а това неизбежно разширява мирогледа. От театър до неорганична химия, от квантова физика, през география, до литература. Това е широкообхватно знание, което стига назад във времето. Яна се докосва до палеографията и старобългарския език, открива голямата метафора на Александрийската библиотека.

И сега като ме питат: нещо ново? Ами нищо ново няма, ние се връщаме там, където е било най-хубаво, там, откъдето сме тръгнали. Александрийската библиотека е символ на безкрайната вселена, извор на вдъхновение и център на всичко. А днес се опитваме да ограничим библиотеката до място, на което се раздават книги и се правят справки. Което не е малко, но не това е основното. Въздухът в библиотеките е друг, отношението към книгите е друго – да си спомним „Името на розата“ на Умберто Еко.

Изобщо, идеята за паметта, за хранилището на познание, което не се интересува от времето, е част от фундамента на цивилизацията. Но и смиряващо преживяване, в което неизбежно става ясно колко дребно е всяко единично човешко усилие.

Библиотеката трябва да бъде храм на знанието, но и на комуникацията, на общуването.

Когато кандидатства за длъжността директор, Яна Кършийска представя мащабния си проект за библиотека, която да функционира като обществено пространство, без изобщо да вярва, че има шанс.

Нямах познанства, нямах лобита. Когато ми се обадиха, че съм избрана, помолих да си проверят пак резултатите, защото нямаше как аз да бъда избрана.

После започва трудното. Постепенното откриване на различни зали, кандидатстването по проекти за средства за интерактивни пространства, обогатяването на художествения фонд, възможността читателите сами да вземат и връщат книги през електронна система, дори хигиенизирането на книгите със специален уред с газ. Пространството предлага дигитални услуги, но в една от залите работи и ретро киномашина.

В Регионална библиотека „Пейо Яворов“ е приветливо и светло като във всекидневна, в читалните има обособени кътове с мека мебел и лампи, може да се видят млади хора с лаптопи и слушалки – чувстват се свободни да откривателстват из архивите с музика, визуални изкуства и литература.

Като дете Яна е била хокана от сърдита библиотекарка, така че нейната революция започва със стандартите, които налага на своя екип – хора основно между 35- и 40-годишни.

В библиотеката трябва да се пази тишина и да се спазва установен ред, но е хубаво да бъде обяснено на читателите защо. И как. Нашите читатели и ние сме в симбиоза, дължим си взаимно уважение.

Извън броя на административните служители екосистемата на библиотеката се поддържа от едва 37 души. Те не само се грижат за съхранението на книгите, а и подсигуряват културната и образователната дейност на пространството. Отново заради вечно актуалната визия за библиотеката като средище. И ако в Александрийската библиотека, основана през III век пр.Хр., по времето на Птолемеите, се е извършвал културен обмен и са се правили научни открития, в по-късните антични и римски библиотеки са били играни театрални постановки и организирани диспути наред с преписването на текстове. Днес Яна Кършийска продължава традицията на допълващите се институции, които са свързани с образованието и културата. Нейната последователност в отстояването на тази концепция променя облика на бургаската библиотека година след година.

Докторантурата, върху която работи Яна Кършийска, е свързана именно със създаването на аватари, които помагат при търсенето на книги в библиотеката. Дигиталните, интерактивни инструменти, които са приятелски ориентирани към младите – това е водещото в подхода ѝ.

Новото поколение е много аналитично и с ясна визия за достъпността, краткостта и обобщеността на информацията. Живеем в безобразен информационен шум. Затова се опитваме да дадем алтернатива, но да сме адекватни на времето.

Самата Яна обаче твърди, че избягва да анализира. Предпочита вдъхновението, емоцията. От преподавателката си в института Ина Андонова научава за разликата между дух и душа. Днес смята, че ако като по-млада е била заета предимно с „трябва“, с работата на духа, днес вече опитва да действа по вдъхновение, да бъде себе си, интуитивно и емоционално. Макар че винаги обмисля план А, В и С. 

Ако трябва да разкаже живота си в образи, ще е през любими книги – детството си свързва с Пърсиг и свободолюбивия дух на „Дзен и изкуството да поддържаш мотоциклет“, младостта – с „Джонатан Ливингстън Чайката“ на Ричард Бах и стихотворението на Емили Дикинсън „От какво се прави ливада“. За по-зрелите си години предпочита сравнението със „Степния вълк“ на Херман Хесе, макар да намира и допирни точки с „Метаморфозата“ на Кафка.

Лудостта и бързината на съвремието ни може да те премажат, ако не обичаш. А какво да обичаш, вече е твое решение. Аз предпочитам природата, книгите и избирателно – хората. Не обичам да внимавам, предпочитам да действам емоционално и ако трябва – да си разбия главата. Но да знам, че съм опитала. Ако сега срещна малкото дете, което съм била, ще му кажа: не слушай никого, прави това, което искаш.

В живота на бързи обороти и гоненето на крайни срокове за изпълнението на проектите си Яна с изумление установява, че докато е работила по своите идеи, губейки представа за времето, тук-там из нейния Бургас са изникнали нови сгради. Местата, които обитава, обикновено са паркът и библиотеката. И една къщичка в Стара планина, защото припознава планината като мечтано убежище.

Корените ѝ по бащина линия са от Северозападна България, от с. Галиче, където са се преселили прадедите ѝ, румънски власи. По майчина линия Яна е наследничка на преселници от Лозенградско. Бургас обаче е мястото, което тя почти не напуска.

Тук работи не просто с партньорски институции, а със съмишленици.

Наистина е много важно да знаеш, че когато вървиш, до теб има хора, за които си сигурен, че ако залитнеш, ще те подпрат. Ще те изправят. Има такива хора около мен и се появиха просто така, не знам кой ги постави на пътя ми.

Човекът, който повярва в мен и прие лудите ми идеи, е нашият кмет – г-н Николов. Нямаше как иначе да се случи денонощната работа на библиотеката.

През годините в Регионална библиотека „Пейо Яворов“ е имало курсове по калиграфия, езиково и компютърно обучение, шах; пространството приютява бургаски клубове и им дава възможност да развиват дейността си в достъпна среда. Тук е сърцето и на Черноморския литературен фестивал, а след двайсетгодишно прекъсване се възстановява и Наградата за научна фантастика „Гравитон“. Предстоят и срещи с корейския театър в партньорство с Корейската национална библиотека.

Мащабът на мислене и действие на екипа на Регионалната библиотека е впечатляващ, но е и доказателство, че съществуват адекватни програми за финансиране.

Често ми се е случвало да ме питат: ама как си го позволи финансово? Всички иновации, които се случват тук, са проектни разходи. Просто се иска труд.

Яна Кършийска е прословута с режима си на перпетуум-мобиле; с половин уста признава, че не ползва отпуск. Но от тази година се учи да ползва съботите и неделите, наложила си е да не говори по телефона по работа. Извежда кучето си или отива в Стара планина, за да релаксира. Смята, че тя я лекува от желанието ѝ да контролира всичко.

Планината е кротка стихия, нито е твърде висока, нито е ниска, тя е естествената очарователна бариера между юга и севера.

Със сигурност обаче на директорката на Регионална библиотека „Пейо Яворов“ ѝ предстои да изпълни още планове, затова ѝ е трудно да назове мечта – Яна Кършийска просто функционира на полето на осъществимите идеи.

Веднъж получих обаждане от г-н Николов – трябваше да отида на среща, за да обсъдим предстоящ проект. В същото време в библиотеката течеше поредната проверка, казах му. Той отговори: „Мислѝ по-широкообхватно.“ Тогава осъзнах, че проверки винаги ще има, междувременно трябва да вършим по-важното.


Хората, които тихо и кротко променят средата, формират общности и задават посоки, в които има смисъл да тръгнем заедно. Тук ви срещаме с тях. Това са „Тези хора“.

Claude Mythos Has Found 271 Zero-Days in Firefox

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/claude-mythos-has-found-271-zero-days-in-firefox.html

That’s a lot. No, it’s an extraordinary number:

Since February, the Firefox team has been working around the clock using frontier AI models to find and fix latent security vulnerabilities in the browser. We wrote previously about our collaboration with Anthropic to scan Firefox with Opus 4.6, which led to fixes for 22 security-sensitive bugs in Firefox 148.

As part of our continued collaboration with Anthropic, we had the opportunity to apply an early version of Claude Mythos Preview to Firefox. This week’s release of Firefox 150 includes fixes for 271 vulnerabilities identified during this initial evaluation.

As these capabilities reach the hands of more defenders, many other teams are now experiencing the same vertigo we did when the findings first came into focus. For a hardened target, just one such bug would have been red-alert in 2025, and so many at once makes you stop to wonder whether it’s even possible to keep up.

Our experience is a hopeful one for teams who shake off the vertigo and get to work. You may need to reprioritize everything else to bring relentless and single-minded focus to the task, but there is light at the end of the tunnel. We are extremely proud of how our team rose to meet this challenge, and others will too. Our work isn’t finished, but we’ve turned the corner and can glimpse a future much better than just keeping up. Defenders finally have a chance to win, decisively.

They’re right. Assuming the defenders can patch, and push those patches out to users quickly, this technology favors the defenders.

News article.

The collective thoughts of the interwebz