Version 6.1.0 of the RPM Package Manager has been released. Notable
changes include the ability to provide modifiers to RPM macros at definition
time, improved build and verification error handling, support for signing files
with PKCS11 tokens using rpmsign, as well as
the addition of several new man pages. The 6.1.0 release also debuts a new release model
inspired by the Linux kernel’s.
As of this writing, 2,346 non-merge changesets have been pulled into the
mainline repository for the 7.3 kernel release. That, clearly, is a mere
down payment on the flood that is to come. Even so, those early pulls
brought in some noteworthy changes, including (but not limited to) a
significant reworking of how group scheduling works on multiprocessor
systems.
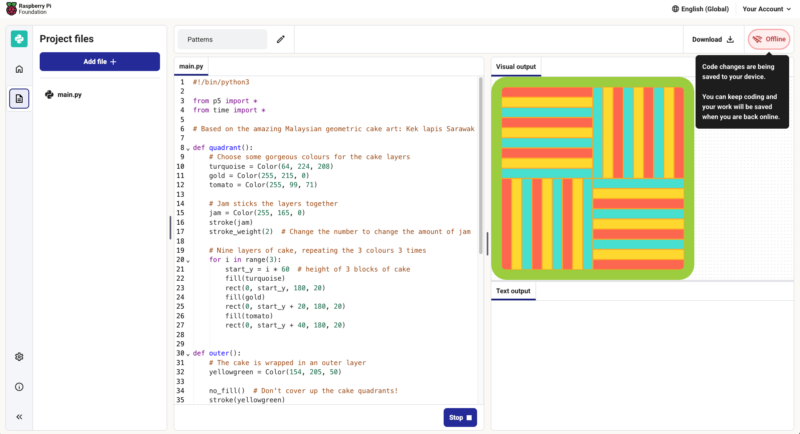
Our free, browser-based Code Editor now keeps working when your internet connection doesn’t. If your connection breaks in the middle of a lesson or a project, you can carry on writing and running your code without disruption, even if the page is reloaded.
Why we built this
An unstable internet connection is a minor annoyance when you’re reading a web page, but it’s a much bigger problem when you’re 20 minutes into creating a program.
Until now, losing your connection while using the Code Editor could mean losing your work: if you refreshed the page at the wrong moment, you might have seen a blank screen or a browser error instead of your program.
Better offline support means the Code Editor can be more useful for learning and teaching.
When we wanted to understand better what learners and educators around the world need from the Code Editor, we carried out research in countries including India, Kenya, and South Africa. One topic we explored was the availability and reliability of internet connections in metropolitan and rural areas. While it was no surprise that internet access is often slow, unreliable, or expensive in rural areas, we learned that issues related to electricity supply, such as load-shedding and brownouts, are also prevalent in metropolitan areas. All this shapes what is realistically possible in a programming activity using an online editor.
And connectivity issues can occur in any school computing lab where 30 learners are all accessing the same WiFi at once, or for a Code Club running off a mobile hotspot in a community centre, or for someone finishing their homework on patchy mobile data.
That’s why it became a priority for us to improve the Code Editor’s offline support by making it resilient to disconnection.
As we describe in our recently shared draft principles for safe and responsible education technology, one of our commitments is to design for diverse needs, abilities, and contexts — including not to assume constant internet connectivity. This Code Editor update is a small, practical piece of that commitment.
What this means for learners and teachers
The Code Editor was built with resilience in mind from the start, for example running code in your browser rather than on a server, and saving your project locally on your device as you go.
Our recent additions ensure that once you’ve opened the Code Editor while online, your browser holds on to even more of the parts you need to keep coding without a connection. Now if you go offline midway through using the Editor:
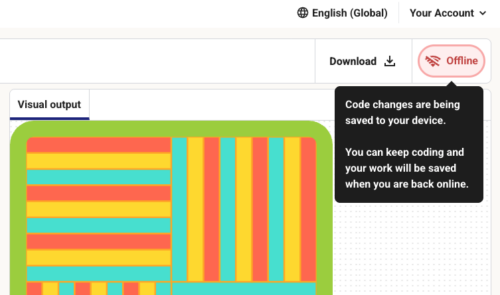
You’ll see a clear message in the Editor flagging that you’re offline
A full page refresh won’t result in a connection error or blank screen
If you’re logged in, everything you do in the Editor while offline is saved to your account automatically once you’re back online
You can still download your code using the ‘download’ button, in case you know you’re going to be offline for a while and need to save your program file on your computer or a storage device
A message shows in the Editor when the internet connection is down.
How it works, in brief
This update is built on a service worker, a script your internet browser runs in the background. When you first load the Code Editor, the service worker stores the files the Editor needs in your browser’s cache. If the network connection then breaks, the service worker serves those stored files instead of trying and failing to fetch them. When you come back online, it automatically refreshes the cache so you’re not left running old files.
What is not possible at the moment
The Code Editor isn’t a full offline app that you install. It’s a browser-based app that we have now upgraded to better cope with losing its internet connection, which means:
You need to have loaded the Code Editor at least once while online, in the browser and on the device you’re going to use
When you go offline, you can’t open projects you haven’t already loaded
If you clear your browser data while offline, any changes you’ve made to projects will disappear
You can’t log into or out of your account while offline, and saving to your account pauses until you’re back online
Any feature that needs the network, such as sharing projects with students in Code Classroom, won’t be available until you reconnect
We’ll keep working to extend what parts of the Editor work offline.
Try it and tell us how you get on
The Code Editor works in your browser with no setup and will always be free for educators and learners. We hope this update makes it more useful for people in lots of different settings.
The update is one of those features some people will never notice, which is rather the point: it should feel like nothing went wrong. If your connection is unreliable and you try out the updated Code Editor, we’d love you to tell us whether or not it works well for you.
We would like to thank Cisco for the generous funding that made this work possible.
A usage policy for Flock license plate reader cameras tells police not to talk about the cameras:
When cops use Flock to arrest someone in Wapello County, Iowa, they don’t want them to know. A usage policy for the automated license plate reader cameras in the county tells police, in no uncertain terms, to keep them a secret: “DO NOT MENTION ALPR USAGE TO THE OCCUPANTS OF THE VEHICLE,” the policy document reads. “DO NOT MENTION ALPR USAGE IN YOUR REPORT OR COMPLAINT UNLESS ABSOLUTELY NECESSARY.”
This reminds me of IMSI-catchers (Stingray was the most popular) a couple of decades ago. Police would go to even more extremes to hide their usage.
In this post, you learn how AgentFlo built intelligent sales agents that convert conversations into completed purchases. We show you how AgentFlo improved revenue performance in early deployments using Amazon Bedrock AgentCore and the Strands Agents SDK.
AgentFlo, the agentic commerce service by Salesflo, helps merchants deploy always-on AI sales, support, and ordering agents across channels like WhatsApp. These agents understand intent, connect to commerce systems, recommend products, create carts, and convert conversations into completed transactions. Today, AgentFlo serves eCommerce merchants managing over $300 billion in annual transacted value, according to Salesflo, across services including Shopify, WooCommerce, Magento, and SAP.
This is Part 1 of a two-part series covering the five pillars of production-grade AI agents. Part 1 covers Velocity, Standardization, and Scalability. Part 2 covers Trust, Reliability, and Business results.
The challenge: customer intent without assistance
Cart abandonment hovers around 70% industry-wide, representing trillions in unrealized revenue annually. For merchants operating on messaging platforms like WhatsApp, the gap widens further:
Cart abandonment: Customers abandon carts because a single question goes unanswered.
Generic product discovery: Ranked listings replace recommendations tailored to each customer.
Missed messaging conversations: Inbound chat volume exceeds staffing capacity across time zones and languages.
No personalized guidance: Most merchants can’t afford 1:1 assistance for every interaction.
Limited outbound engagement: Teams lack bandwidth for proactive sales motions.
Peak traffic spikes: Flash sales and seasonal campaigns can spike traffic 10–50x beyond normal capacity.
Rule-based chatbots can’t handle nuanced sales conversations. Human agents can’t scale across geographies, languages, and time zones. Merchants need specialized AI sales agents that understand customer context, run complex workflows, and operate autonomously 24/7.
What makes an agent?
At its simplest, an agent combines a model, instructions, tools, context, and memory. The model reasons over a user’s request. The instructions define the agent’s role and the limits of what it should do. Tools let the agent take action in the real world. Context grounds it in business-specific data. Memory keeps the conversation coherent across turns.
In AgentFlo, those abstract components map to concrete pieces of the platform:
Component
What it does in AgentFlo
Model
Understands user intent and decides what to do next
System prompt / persona
Defines whether the agent behaves like a sales agent, restaurant agent, support agent, or receptionist
Tools
Allow the agent to search products, check inventory, create carts, place orders, raise tickets, or trigger follow-ups
Knowledge
Grounds responses in merchant-specific data such as product catalogs, menus, policies, promotions, and FAQs
Memory / state
Maintains conversation history, cart state, customer preferences, and previous actions
Channels
Connects the agent to WhatsApp, SMS, RCS, web chat, and voice
Guardrails / Policy
Prevents unsafe, unauthorized, or incorrect actions
Observability
Tracks cost, performance, conversions, and conversation quality
Building a demo agent is straightforward. Building one that runs a business safely, repeatably, and at scale requires a different approach. AgentFlo organizes this approach around five pillars.
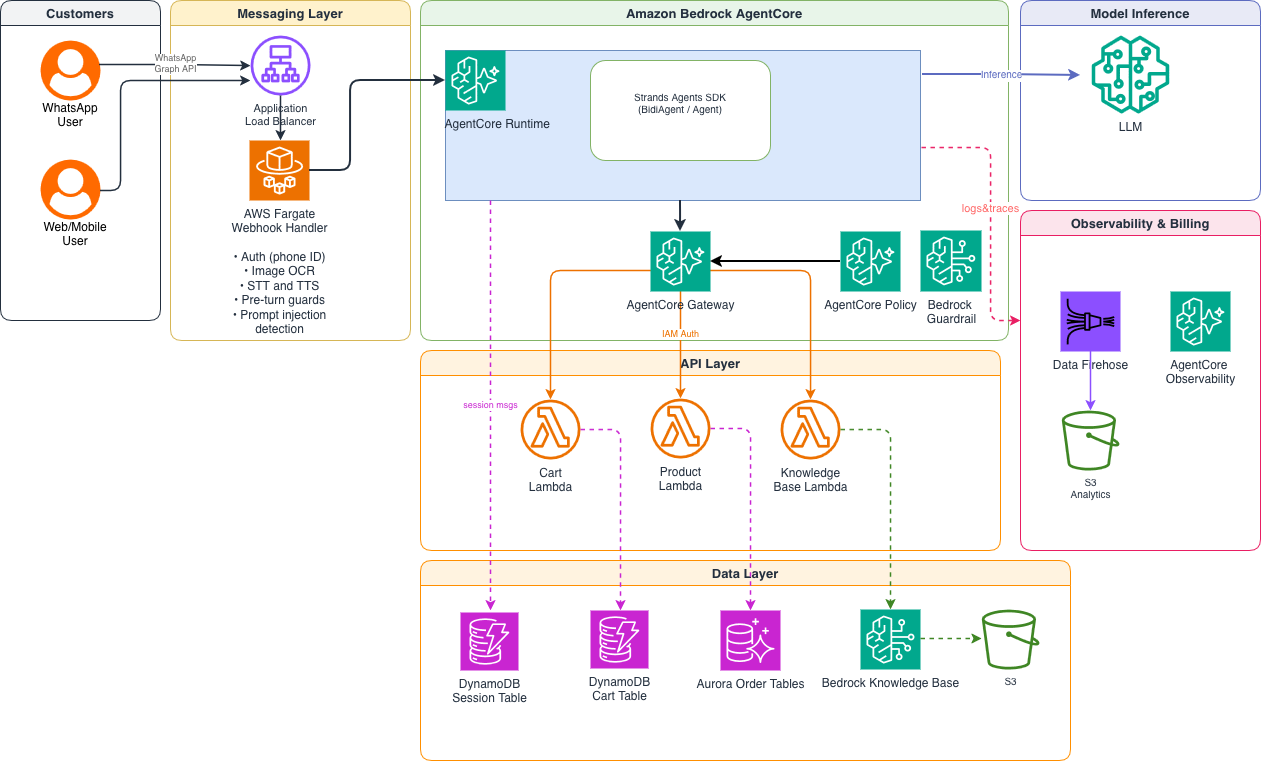
Figure 1: AgentFlo’s production architecture on AWS.
Customer messages arrive through WhatsApp Graph API or web/mobile channels and pass through an Application Load Balancer into the AWS Fargate messaging layer. It handles authentication, image optical character recognition (OCR), speech-to-text/text-to-speech, pre-turn guardrails, and prompt injection detection. Validated requests flow into AgentCore runtime, a capability of Amazon Bedrock AgentCore, where the Strands Agents SDK orchestrates an agent that streams model inference to an external large language model (LLM). AgentCore Gateway, a capability of Amazon Bedrock AgentCore, brokers tool calls, with IAM-based authorization, to an API layer of AWS Lambda functions (Cart, Product, and Knowledge Base). It persists state across a data layer comprising Amazon DynamoDB session and cart tables, Amazon Aurora order tables, and an Amazon Bedrock Knowledge Base backed by Amazon S3. Policy in Amazon Bedrock AgentCore enforces deterministic access control independently of model reasoning. Amazon Bedrock Guardrails can also be embedded in Policy to filter prompt attacks, harmful content, and sensitive information on both requests and responses. On the observability side, logs and traces feed into AgentCore Observability, a capability of Amazon Bedrock AgentCore, while Amazon Data Firehose captures every interaction into Amazon S3 for cost and revenue analytics.
AgentFlo evaluated several hosting options before selecting Amazon Bedrock AgentCore. Three capabilities made the difference:
Stateful sessions for long-running commerce conversations.
Agent runtime: each agent session runs in its own lightweight virtual machine, providing hardware-level security boundaries between tenants.
Native MCP integration: Model Context Protocol (MCP) is an open standard that allows AI agents to connect securely to external data sources and tools through a unified interface. AgentCore Gateway supports MCP natively for standardized tool connectivity.
Pillar 1: Velocity: from merchant idea to live agent in minutes
Speed to market determines whether merchants can capture emerging opportunities. AgentFlo addresses this with a streamlined deployment model.
The challenge
Merchants want to launch agents quickly, but each has unique workflows, tone, tools, languages, products, and business rules. Generic chatbot templates are too shallow. Custom-building each agent doesn’t scale.
Recipe-based deployment
AgentFlo uses a recipe-based agent deployment model. Merchants select from pre-configured recipes, each shipping with persona, language, tone, tool sets, prompt templates, knowledge sources, response packs, and business rules. Available recipes include:
Sales agent.
Restaurant ordering agent.
Clinic receptionist.
Support agent.
B2B reorder agent.
Cart recovery agent.
Merchants fine-tune a few choices in the AgentFlo Portal. The rest is automated.
How it works
AgentFlo chose Strands Agents SDK as its agent framework. Strands Agents SDK uses a model-driven architecture: you define tools as Python functions, write a system prompt, and let the model handle orchestration. No rigid workflow graphs or hand-coded state machines.
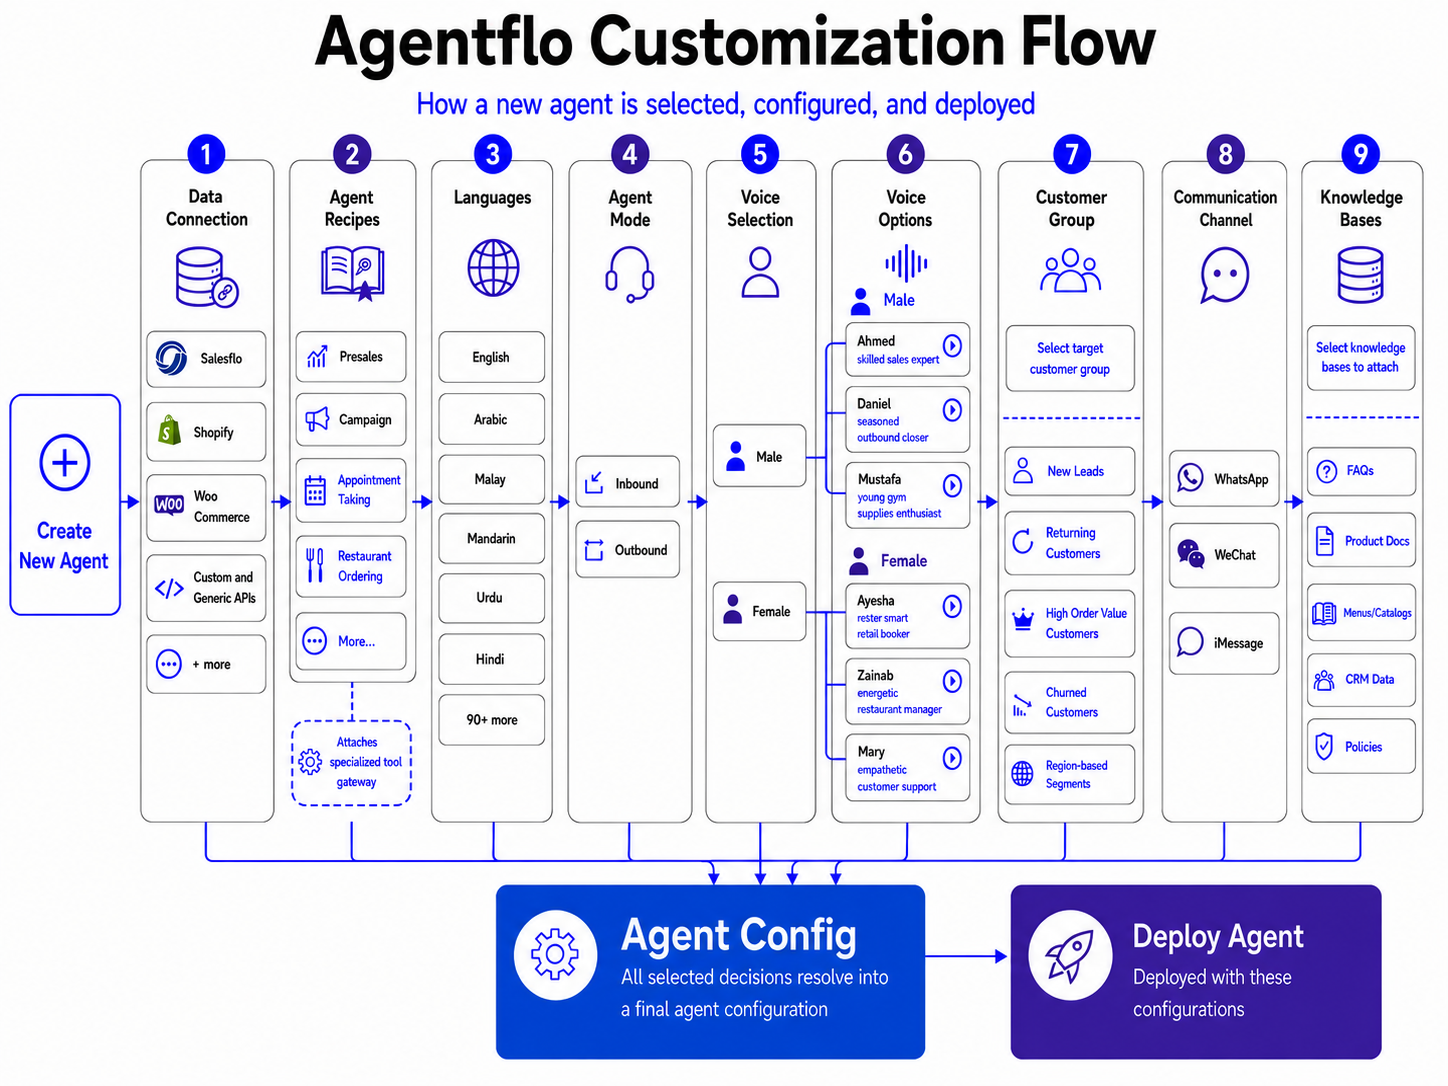
From the merchant’s perspective, agent creation is entirely no-code. Here’s an example of the agent customization flow:
Figure 2: Agent customization workflow
This approach makes the recipe model work. Adding a new capability (like loyalty program enrollment) means writing a new tool function and updating the system prompt. No orchestration layer rewiring is needed.
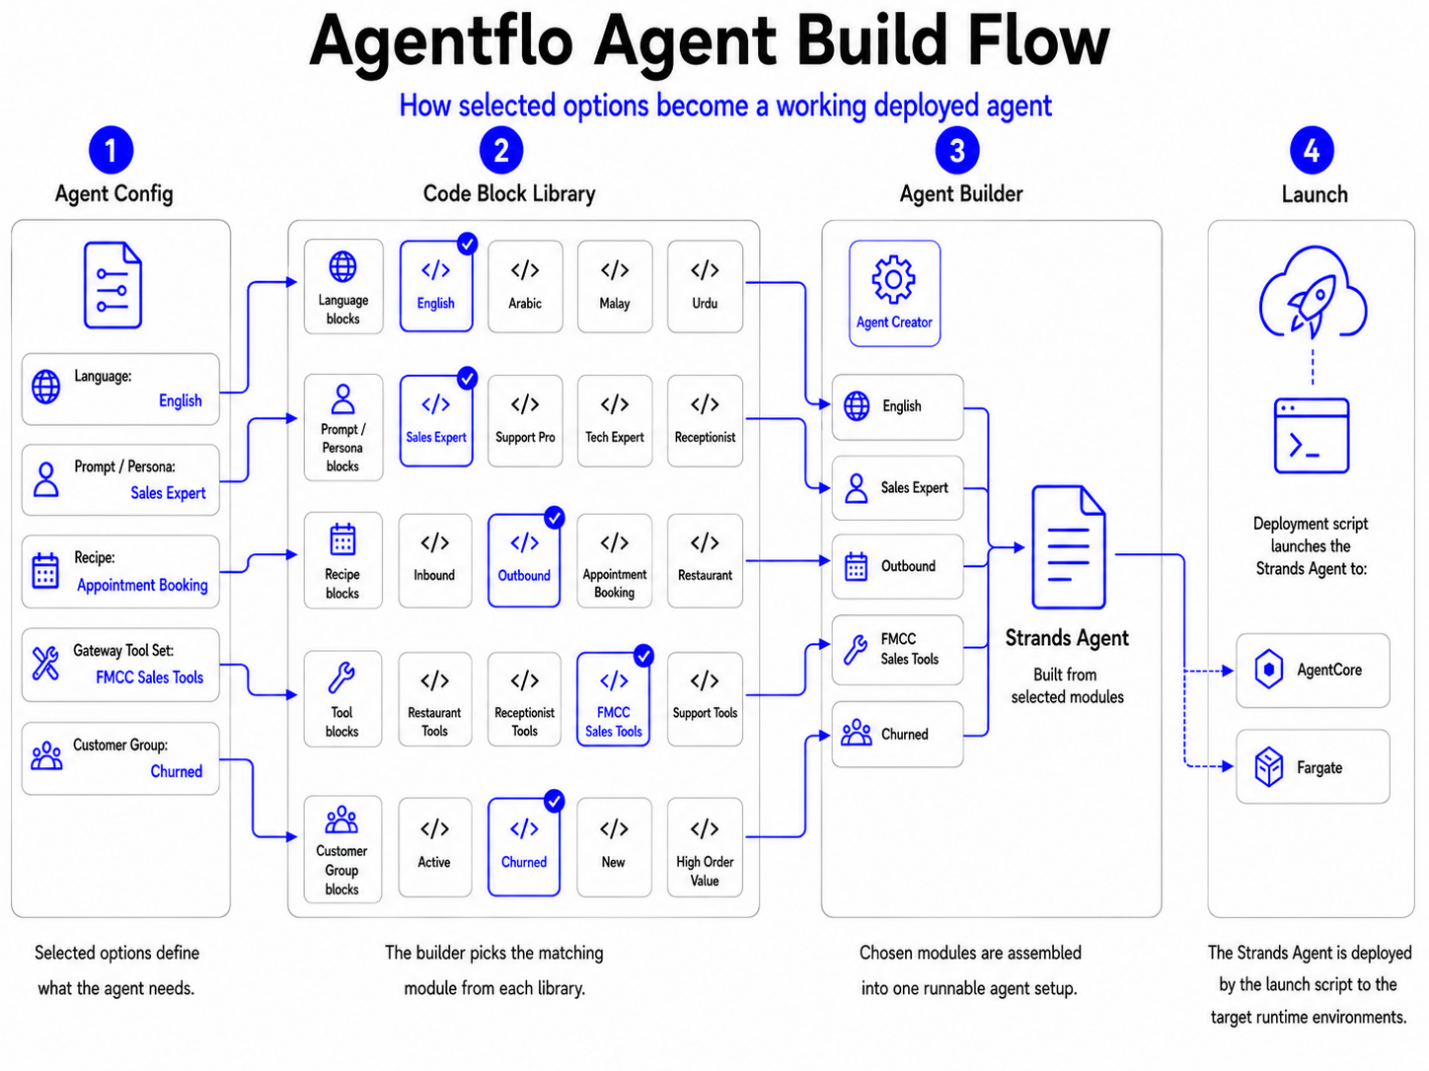
Behind the scenes, one selection triggers an automated pipeline:
The portal generates a Strands agent configuration from the recipe template.
GitHub Actions packages the agent (tools, prompts, context) into a container.
The container deploys to AgentCore runtime with appropriate Gateway policies.
The agent goes live on WhatsApp within minutes.
Figure 3: How to build a customized agent under hook workflow
Each agent is a Strands Agent instance with tool definitions mapped to AgentCore Gateway endpoints. Extending an agent’s capabilities is a code change, not an architectural one.
Results
This recipe-based approach delivers faster merchant onboarding, rapid experimentation with new agent behaviors, and quick addition of new capabilities platform-wide. It also means lower engineering effort per deployment and a tighter feedback loop between customer conversations and product iteration.
Pillar 2: Standardization: reusable recipes, tools, and commerce workflows
Consistency across deployments speeds iteration and reduces maintenance burden. AgentFlo achieves this through shared building blocks.
The challenge
As AgentFlo expanded across industries, fragmentation threatened to slow the team down. Every merchant has unique catalog structures, ERP setups, system configurations (Shopify, WooCommerce, Magento), pricing rules, languages, promotions, and support processes. Without standardization, every deployment becomes a custom project, and custom projects don’t scale to hundreds of merchants.
Repeatable building blocks
AgentFlo standardizes around several core components: agent recipes (domain-specific templates), a tool marketplace (reusable capabilities), MCP-based connectors (standardized integrations), integration contracts (consistent interfaces). Additional components include prompt and context packs (reusable templates), conversation review loops (continuous improvement), and a shared semantic layer (unified product understanding). Merchant-specific complexity is pushed to the system edges. The core remains consistent.
Single-agent architecture with domain expertise
We learned early on that a single agent with domain-specific knowledge and a curated tool set outperforms multi-agent architectures for most customer interactions. Each AgentFlo deployment configures a distinct persona, voice, language, and specialized tool set tailored to the business domain (sales agent, restaurant agent, clinic receptionist). It ships with curated contexts, prompt templates, and response packs. Merchants deploy these domain-specific agents through the self-service portal.
A single focused agent maintaining unified context converts better than multiple generalists coordinating with each other. Multi-agent capabilities remain available where valuable. For example, when conversations transition from sales to support, context hands off cleanly to the specialist agent.
Tool routing through AgentCore Gateway
Centralized tool management routes agent requests to dedicated AWS Lambda functions. When a customer asks about product availability, the agent queries the product catalog. When they’re ready to buy, it handles cart operations. For personalized recommendations, it retrieves data from Amazon Bedrock Knowledge Bases, the fully managed Retrieval Augmented Generation (RAG) capability, backed by merchant data stored in Amazon S3. Sales intelligence APIs provide additional context for each interaction.
OAuth tokens and platform credentials live in the Gateway, not in agent sessions. Policy in AgentCore sits alongside the Gateway, enforcing fine-grained, Cedar-based access control rules that operate independently of model reasoning. Cedar is an open-source policy language developed by AWS that allows fine-grained, verifiable authorization decisions.
Policies define which agent sessions can invoke which tools. For example, a sales agent can’t call customer-support-only APIs.
For standardization, this means every new tool added to the platform (payment integration, shipping provider, loyalty system) becomes available to every applicable recipe through the same mechanism. Tools aren’t re-implemented per merchant.
AgentCore Gateway as the integration backbone
AgentFlo integrates with dozens of eCommerce services: Shopify, WooCommerce, Magento, SAP, payment processors, shipping providers, and loyalty systems. Each integration is defined as an MCP server connector, with Gateway handling discovery, authentication, and routing. Furthermore, AgentFlo has many different agent recipes, each with their own specialized tool packs to provide that functionality. To make these connections modular and efficient, AgentFlo uses AgentCore Gateway.
From the agent’s perspective, the full Gateway tool surface is reachable in a few lines:
from strands import Agent
from strands.models import BedrockModel
from strands.tools.mcp.mcp_client import MCPClient
from mcp.client.streamable_http import streamablehttp_client

def create_transport():
    return streamablehttp_client(
        GATEWAY_URL,
        headers={"Authorization": f"Bearer {access_token}"},
    )

mcp_client = MCPClient(create_transport)

with mcp_client:
    # Discover every tool registered on the Gateway in one call.
    # cart, product catalog, knowledge base, shipping, loyalty, etc.
    tools = mcp_client.list_tools_sync()

    agent = Agent(
        model=BedrockModel(model_id="us.anthropic.claude-sonnet-5-20260630"),
        tools=tools,
        system_prompt=SALES_AGENT_PROMPT,
    )

    response = agent("Do you have the red leather wallet in stock?")
Connecting a Strands agent to AgentCore Gateway. A single list_tools_sync() call gives the agent every integration registered on the Gateway: cart, product catalog, knowledge base, shipping, loyalty. Onboarding a new service for a merchant is a Gateway change, not an agent change.
Key capabilities:
MCP-native tool connectivity: Each platform or tool set integration is a standard MCP server connector.
OAuth and credential management: Platform API keys and OAuth tokens are managed centrally in Gateway, never exposed to individual agent sessions.
Code simplicity: The code is cleaner, shorter, and more modular, which simplifies configuration for scale. The alternative is extensive local code for each connection or tool set.
Because each new service integration and recipe-specific tool set is defined as an MCP server connector in AgentCore Gateway, expansion is modular and quick. Adding a new service or tool set requires a connector definition, not a re-architecture.
Conversation reviews as a standardization loop
Standardization also comes from learning. AgentFlo continuously reviews real conversations to understand how customers ask for products, where they drop off, which recommendations convert, when handoff is needed, and how local language affects buying behavior.
These reviews feed back into recipes, prompts, and tool definitions. Standardization is something the platform earns over time, not something declared at launch.
Results
Every deployment improves future deployments, and new integrations become reusable across the merchant base. Agent behavior stays consistent across recipes and merchants, and workflows become repeatable across industries. The service becomes harder to replicate because it learns from real commerce behavior, not generic templates.
Commerce conversations are unpredictable in volume and duration. AgentFlo’s architecture handles both dimensions without manual intervention.
The challenge
During flash sales, product launches, or restaurant rush hours, customer conversations can spike 10–50x. Human teams can’t scale that fast. AgentFlo must also support many merchants and concurrent customer sessions simultaneously. One merchant’s surge can’t affect another’s experience.
AgentFlo’s serverless architecture
AgentFlo uses a serverless architecture. Message ingestion, agent execution, tool execution, state, analytics, and billing each scale independently. Each layer absorbs its own spikes without requiring the rest of the system to over-provision.
AgentCore runtime properties for scale
Several AgentCore runtime properties specifically support scale:
Isolated microVM execution: Each agent session runs in its own environment with dedicated CPU, memory, and filesystem. The environment is sanitized on termination. One merchant’s sessions never interfere with another’s.
Stateful sessions up to eight hours: Long-running conversations don’t lose context. A customer browsing in the morning can continue the same assisted session that evening.
Framework-agnostic: AgentCore runs Strands Agents natively but also supports any containerized agent framework, giving AgentFlo flexibility to evolve the agent architecture over time.
How it works
The architecture is built end-to-end on AWS:
Messaging layer (AWS Fargate): An Application Load Balancer routes incoming WhatsApp messages to a Fargate application that handles authentication, voice message conversion (Opus OGG to MP3 transcription with fuzzy matching for product name recognition). The application also runs pre-turn security guards. AWS End User Messaging provides an alternative channel option for broader reach.
Agent orchestration (Amazon Bedrock AgentCore runtime): Each customer session spawns an isolated agent instance running the Strands Agents SDK. Sessions are stateful for up to eight hours and isolated through microVM architecture, where each session runs in its own lightweight virtual machine. They are persistent, with filesystem access for intermediate results and cached product catalogs. microVM isolation keeps merchants completely separated.
This is the entire bridge between Strands SDK agent code and a production-ready endpoint on AWS:
from strands import Agent
from bedrock_agentcore.runtime import BedrockAgentCoreApp

app = BedrockAgentCoreApp()

agent = Agent(
    tools=tools,  # from the Gateway, per snippet above
    system_prompt=SALES_AGENT_PROMPT,
)

@app.entrypoint
def invoke(payload, context):
    """One AgentCore session per customer conversation."""
    user_message = payload.get("prompt")
    session_id = getattr(context, "session_id", None)  # stable for up to 8 hours
    result = agent(user_message)
    return {"result": result.message}

if __name__ == "__main__":
    app.run()
This is all the glue between a Strands agent and AgentCore Runtime. BedrockAgentCoreApp wraps the agent in the standard /invocations contract, and AgentCore handles microVM provisioning, session isolation, scaling, and stateful sessions up to eight hours. Two CLI commands take it from a local file to a live endpoint on AWS. No Dockerfile, no API routing, no web framework to maintain.
Tool execution (Amazon Bedrock AgentCore Gateway): Tool calls scale separately from agent reasoning, so a sudden burst of cart operations doesn’t slow down the agent loop itself.
Results
The architecture handles peak traffic without pre-provisioning capacity and supports long-running conversations that survive across visits. It provides strong multi-merchant isolation with lower operational overhead than traditional always-on infrastructure, resulting in a better customer experience during high-intent moments like product launches or flash sales.
What’s next
In Part 2 of this series, we explore:
Pillar 4: Trust. Guardrails for autonomous commercial action and real-time visibility into agent operations.
Pillar 5: Reliable. Data foundation that ensures agents act on reliable, up-to-date information to complete tasks with precision.
Business results: Measurable impact across the customer lifecycle.
Future roadmap: Voice agents, server-side tool execution, and integration expansion.
Summary
In this post, we explored three of the five pillars for building production-grade AI agents:
Velocity: How recipe-based deployment allows merchants to launch AI sales agents in minutes using the model-driven architecture of the Strands Agents SDK.
Standardization: How reusable building blocks and centralized tool management through Amazon Bedrock AgentCore create consistency across hundreds of deployments.
Scalability: How AgentFlo handles elastic, stateful commerce conversations at scale through Amazon Bedrock AgentCore and AWS Fargate.
Amazon SageMaker Unified Studio is a single data and AI development environment that brings together data preparation, analytics, and machine learning (ML) development in one place. By unifying these workflows, it saves teams from managing multiple tools and makes it straightforward for data scientists, analysts, and developers to build, train, and deploy ML models while collaborating. In Amazon SageMaker Unified Studio, a domain is the organizing entity for connecting your assets, users, and their projects. With Amazon SageMaker unified domains, you have the flexibility to reflect the data and analytics needs of your organizational structure. You can create a single unified domain for your enterprise or multiple domains for different business units.
Some enterprises, especially those in regulated industries, might require limiting access to trusted networks (such as VPN CIDRs) or to managed devices that meet compliance standards through device attestation.
In this post, we demonstrate how to integrate SageMaker Unified Studio as a custom SAML application and apply conditional access policies for enforcing device compliance, IP-based restrictions, or multi-factor authentication (MFA). For this post, we use Okta as the identity provider (IdP).
Solution overview
This solution demonstrates how to integrate Amazon SageMaker Unified Studio (SMUS) with external SAML identity providers such as Okta. The integration enforces enterprise security controls, including trusted network access, device compliance, and multi-factor authentication. With this integration, organizations in regulated industries can maintain strict access controls while providing single sign-on for their data science and AI development teams. By using SAML 2.0 federation with conditional access policies, you can help make sure that only authenticated users on compliant devices from trusted networks gain access. This access applies to your SageMaker Unified Studio domains and the associated data and AI workloads.
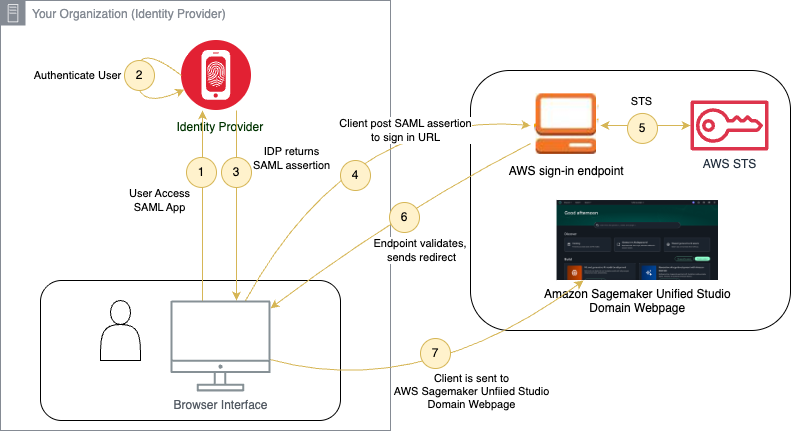
Authentication flow for accessing SageMaker Unified Studio through SAML
The architecture diagram illustrates the secure authentication flow for accessing SageMaker Unified Studio through SAML integration:
Users typically initiate access from corporate-managed devices through VPN or trusted network connections.
The IdP authenticates the user and evaluates conditional access policies defined by your organization. Based on these policies, it checks for trusted devices, approved source IP ranges, and MFA completion. If any policy fails, the login is rejected. Otherwise, authentication proceeds.
Upon successful authentication and policy validation, the IdP generates a digitally signed SAML assertion containing user attributes and group memberships, securely delivering it to the user’s browser through HTTP POST binding.
The client browser automatically posts the SAML assertion to the AWS Security Token Service (AWS STS) sign-in endpoint. There, the AWS IAM Identity Provider validates the trust relationship with your corporate IdP through pre-configured SAML federation settings.
AWS STS validates the SAML assertion signature and authenticity. It then maps the user attributes to a specifically configured IAM role with SageMaker Unified Studio permissions, including the datazone:GetIamPortalLoginUrl permission required for domain access.
AWS STS confirms successful role assumption and generates temporary AWS credentials with a defined session duration. It then issues an HTTP redirect that returns the browser to the SageMaker Unified Studio domain with authenticated session tokens.
Users gain access to the unified environment for data preparation, analytics, and machine learning development. All activities are governed by the assumed IAM role permissions and logged for comprehensive audit trails.
Walkthrough
In this walkthrough, you create a SAML application in Okta, connect it to AWS, and configure a SageMaker Unified Studio domain to use it for authentication.
Prerequisites
Before you get started, make sure you have the following:
Familiarity with Amazon SageMaker Unified Studio.
A basic understanding of SAML 2.0.
AWS Identity and Access Management (IAM) permissions to create a domain in Amazon SageMaker Unified Studio.
Access to your SAML IdP (such as Okta or Entra ID) to create and configure a SAML application.
Step 1: Create an application in Okta
The first step is to set up a new SAML application in Okta that manages authentication for SMUS.
In Okta, go to Applications → Create App Integration, and choose SAML 2.0.
Provide an App name.
Set the Single sign-on URL to https://signin.aws.amazon.com/saml.
Set Name ID format to Persistent.
Set the Audience URI (SP Entity ID) to https://signin.aws.amazon.com/saml.
Choose Next, and finish creating the application.
Once created, copy the Metadata URL and Sign On URL. You need these in later steps.
Step 2: Create an identity provider in IAM
Now, let’s connect Okta to AWS by creating an IAM identity provider. This allows AWS to trust authentication responses from Okta.
Replace <REGION>, <ACCOUNT-ID>, and <DOMAIN-ID> with the corresponding values from your SageMaker Unified Studio domain ARN (arn:aws:sagemaker:<REGION>:<ACCOUNT-ID>:domain/<DOMAIN-ID>). You can find the domain ARN in the SageMaker console under Domains.
Step 4: Configure SAML assertions
To make sure AWS understands who is signing in, configure the SAML assertions in Okta.
Finally, let’s set up the SMUS domain and tie it all together.
Note: Creating a SageMaker Unified Studio domain incurs charges. For pricing details, see the Amazon SageMaker pricing page.
Open the Amazon SageMaker console.
Choose Create domain.
Choose Manual setup (this allows for SAML integration).
Enter a domain name, then choose Create.
In Configure SSO user access, select SAML, then choose Next.
Set the IdP SSO URL to the Sign On URL from Step 1.
Select Do not require assignments. (Access is instead managed by your IdP team through Okta or Entra.)
Choose Next, then choose Save.
To verify the integration works, open your SMUS domain and choose Sign in with SSO. You are redirected to Okta, and conditional access policies such as VPN, device attestation, or MFA apply automatically.
Open your SMUS domain URL in a browser.
Choose Sign in with SSO.
Confirm that you are redirected to Okta for authentication.
Sign in with your Okta credentials.
Verify that you are redirected back to the SMUS domain with access to your projects.
Step 6: Assign users to the Okta application
Before users can authenticate through Okta to access SMUS, you must assign them to the application.
In Okta, navigate to your SAML application.
Go to the Assignments tab.
Choose Assign, and select Assign to People or Assign to Groups.
Select the users or groups who need access to SMUS.
Choose Save and Go Back, then choose Done.
Step 7: Apply conditional access policies
Up to Step 5, we configured SMUS with an external SAML IdP. At this point, anyone assigned to the new application in your IdP can sign in and access the SMUS domain.
This is where conditional access policies come into play. Based on your organization’s governance model, you can add policies in your IdP to further control how and when users gain access. For example:
Restricting access to specific corporate IP address ranges (for example, only through VPN).
Enforcing device compliance so that only managed or secure devices can connect.
Adding MFA requirements for sensitive actions.
Applying device attestation to help assess whether the endpoint conforms to security baselines.
Most major IdPs, including Okta and Entra ID, support conditional access. You can find more details in their documentation:
These policies allow you to enforce the right level of protection, from something as simple as requiring users to connect through corporate networks to something as advanced as verifying device attestation across your fleet.
Clean up
To avoid incurring ongoing charges, delete the resources you created during this walkthrough:
Delete the Amazon SageMaker Unified Studio domain from the SageMaker console.
Delete the IAM role you created for Okta.
Delete the IAM identity provider.
Delete the SAML application in Okta.
Important: Deleting the SMUS domain permanently removes all projects, assets, and data within it. Back up any important work before proceeding.
Conclusion
By integrating SMUS with an external IdP through SAML, you can help enforce modern access controls based on your organization’s security requirements. This post walked through how to configure SMUS with a custom SAML application and pointed you toward resources for setting up conditional access policies.
With conditional access in place, you can decide, based on your organization’s needs, whether access should be limited to trusted users on trusted networks, trusted devices, or both. This approach can help provide a more secure and compliant login experience that aligns SMUS access with your company’s broader identity and security strategy.
Go 1.27, the most recent version of
the Go programming language, has been released
with a number of new tools, the addition of support for the ML-DSA post-quantum algorithm,
new JSON-processing packages, language updates, and more.
Greg Kroah-Hartman has announced the release of the 7.1.9, 6.18.45, 6.12.104, 6.6.152, 6.1.183, 5.15.216, and 5.10.265 stable kernels. Each contains important
fixes throughout the tree; users are advised to upgrade.
The Debian Project is voting on the usage
of large language models (LLMs) to make contributions to the project. The first
proposal, sent in late July by Matthias Geiger, would expressly forbid any
contributions to Debian that are created by or with the assistance of LLMs. That
kicked off a firestorm of discussion and a flood of alternate proposals. Debian
developers are now voting on
eight proposals in total that range from banning LLM-assisted contributions
to explicitly approving them, as well as the standard “none of the above” option
that would leave Debian with no agreed policy.
Many teams now deploy AI agents that pull from Amazon DynamoDB tables, document repositories, software as a service (SaaS) platforms, and internal knowledge bases to answer questions and automate workflows. A key risk in these deployments is that the agent has no awareness of who’s asking, so it might return data the user shouldn’t see.
If you’re using Amazon Bedrock AgentCore to build AI agents that access multiple data sources, you need each user to see only the data they’re authorized to access. In this post, you learn patterns for propagating user authorization context through your agents so access control is enforced by infrastructure and downstream services, not by agent code. In this post, we show you how to deploy agents that enforce least privilege access without writing authorization logic in the agent itself. This approach follows AGENTSEC03 best practice in the AWS Well-Architected Agentic AI Lens.
Use case
Consider an example of a customer relationship management (CRM) chat application where employees from Sales and Finance departments interact with an AI agent to access customer information. Employees use the same chat interface and the same agent, but each department needs isolated access to their respective data:
Sales needs access to customer contracts, pricing strategies, and sales pipeline data
Finance needs access to customer invoices, payment records, and financial reports
The AI agent accesses three types of data sources on behalf of users:
Customer records in Amazon DynamoDB, partitioned by department
When a Sales employee asks, “Show me customer contracts,” the agent must retrieve only Sales department contracts, not Finance invoices. This enforcement must happen outside the agent so that even if the agent is compromised through prompt injection or application bugs, it can’t access unauthorized data.
Note: Although we use department-based scoping in this example, the pattern generalizes to any custom claim you define, whether it represents a role, business unit, geographic region, or project assignment.
Architecture overview
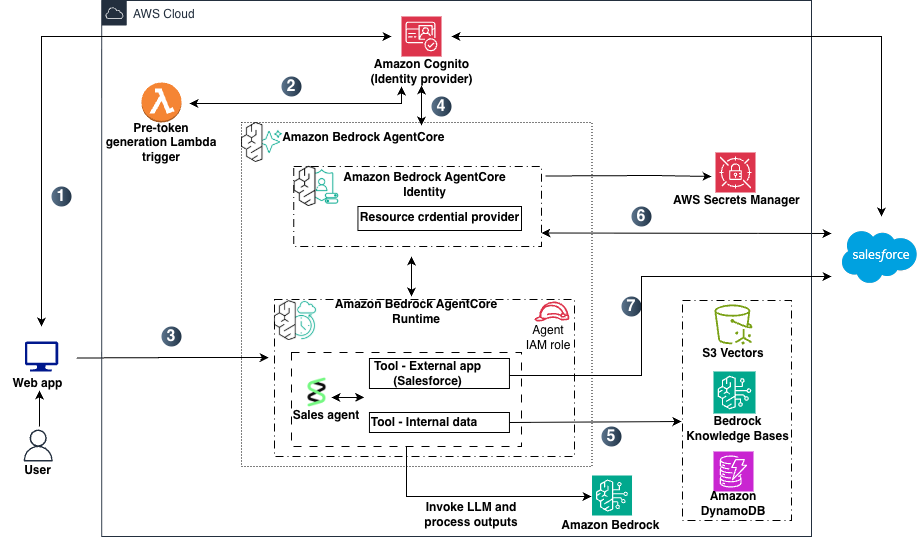
The following diagram shows the architecture used in this demonstration.
Figure 1: Target architecture
The data flow shown in Figure 1 includes:
A user opens the chat application and authenticates with Amazon Cognito user pool , which acts as the identity provider (IdP).
A pre token generation Lambda trigger (V2) enriches the JSON Web Tokens (JWTs) with a custom claim and AWS session tag metadata before returning them to the user.
The web app routes the user’s request along with the access token to the agent deployed on Amazon Bedrock AgentCore Runtime.
Bedrock AgentCore Runtime validates the inbound JWT and, through Bedrock AgentCore Identity, issues a workload access token that binds the user and agent identities, and then invokes the agent.
For queries requiring internal documents, the agent uses its AWS Identity and Access Management (IAM) role to query Amazon Bedrock Knowledge Bases (backed by an Amazon S3 vector store) with metadata filtering, and DynamoDB with user-scoped session-tagged credentials.
The agent calls the Salesforce REST API using the user-scoped token. Salesforce applies sharing rules and returns only records the user is authorized to access.
This architecture follows two key principles.
The agent acts as an orchestrator, not a gatekeeper; it coordinates tool calls and reasoning but doesn’t control access to data. Authorization is enforced by downstream services.
The agent doesn’t store credentials to data stores; instead, each request gets temporary, user-bound access tokens.
In the following sections, we dive deep into each data source to show how these principles are achieved in practice.
Initial user authentication with IdP
When an employee opens the chat application, they authenticate using their corporate credentials. For this example, you use Amazon Cognito user pools as the IdP. You can also achieve this with other IdPs such as Entra ID or Okta.
The pre token generation Lambda trigger (V2) captures the user’s custom department context and adds it to the tokens to both the identity (ID) token and access token that Bedrock AgentCore Runtime uses for authorization decisions each serving a distinct purpose. The access token is used by the Bedrock AgentCore Runtime custom JWT authorizer for inbound authorization. The ID token also receive the https://aws.amazon.com/tags claim (used by AWS Security Token Service (AWS STS)) for session tags). The https://aws.amazon.com/tags claim is the specific format required by AWS STS to extract session tags during AssumeRoleWithWebIdentity. For more information and step-by-step guidance see How to customize access tokens in Amazon Cognito user pools.
The following example shows the key logic within a pre token generation Lambda handler function configured as a trigger on your Amazon Cognito user pool. This code runs automatically when a user authenticates, extracting their department attribute and adding it as a custom claim to both ID Token and access token.
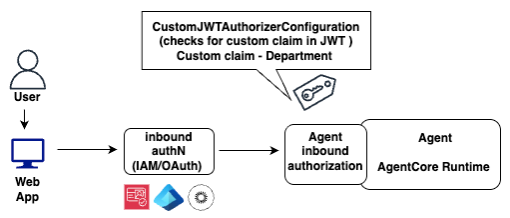
When the user request reaches AgentCore Runtime, the Inbound JWT authorizer performs two checks as shown in Figure 2. It validates the JWT token with Amazon Cognito (the configured IdP) by cryptographically verifying the token’s signature, confirming it is non-expired, and checking it was issued by the trusted IdP. It then extracts the department claim from the validated token and compares it against the expected value configured in the authorizer, any token without a matching claim is rejected before the agent code is invoked.
Figure 2: Inbound JWT authorization
The following example shows the inbound JWT authorizer configuration that you pass when deploying your agent to AgentCore Runtime. This configuration tells AgentCore which IdP to validate against and which custom claim value to enforce for this agent. In this example, inboundTokenClaimName is department, inboundTokenClaimValueType declares the claim type as STRING_ARRAY, and authorizingClaimMatchValue specifies the allowed values ([“Sales”, “Finance”]) with the CONTAINS_ANY operator. The authorizer validates that the department claim is present in the token and matches one of these values, ensuring only authenticated users from the Sales or Finance department can invoke the agent.
Note: AgentCore Runtime automatically creates a workload identity for each deployed agent. A workload identity represents the digital identity of your agents within the AWS environment. It allows agents to maintain consistent identity whether they’re using IAM roles for AWS resource access, OAuth 2.0 tokens for external service integration, or API keys for third-party tool access.
Passing the user context for agent outbound authorization
After the inbound JWT token is validated and the user’s authorization context is confirmed, the agent must propagate this context to downstream resources. The fundamental security challenge here is how to design a system so that an agent acting on behalf of a user can only access data that user is authorized to see, even if the agent itself is compromised.
The traditional approach of granting the agent broad credentials and relying on application-level filtering (such as adding WHERE clauses to queries) creates a single point of failure. If an attacker manipulates the agent through prompt injection or exploits a bug in the filtering logic, the full dataset becomes accessible. A more resilient design moves authorization enforcement out of the agent’s application code and into the infrastructure layer wherever possible. Instead of trusting the agent to filter results correctly, you configure the underlying services—IAM policies, database access controls, SaaS sharing rules—to reject unauthorized requests regardless of what the agent asks for. This way, the agent’s credentials are inherently limited to the requesting user’s permissions, and no amount of prompt manipulation can bypass those boundaries. Where infrastructure-level enforcement isn’t yet available, such as metadata filtering in Amazon Bedrock Knowledge Bases, the agent applies application-layer controls as a complementary measure. The following sections demonstrate how this principle applies to each data source in our architecture.
Pattern 1: Scoping DynamoDB access to the requesting user
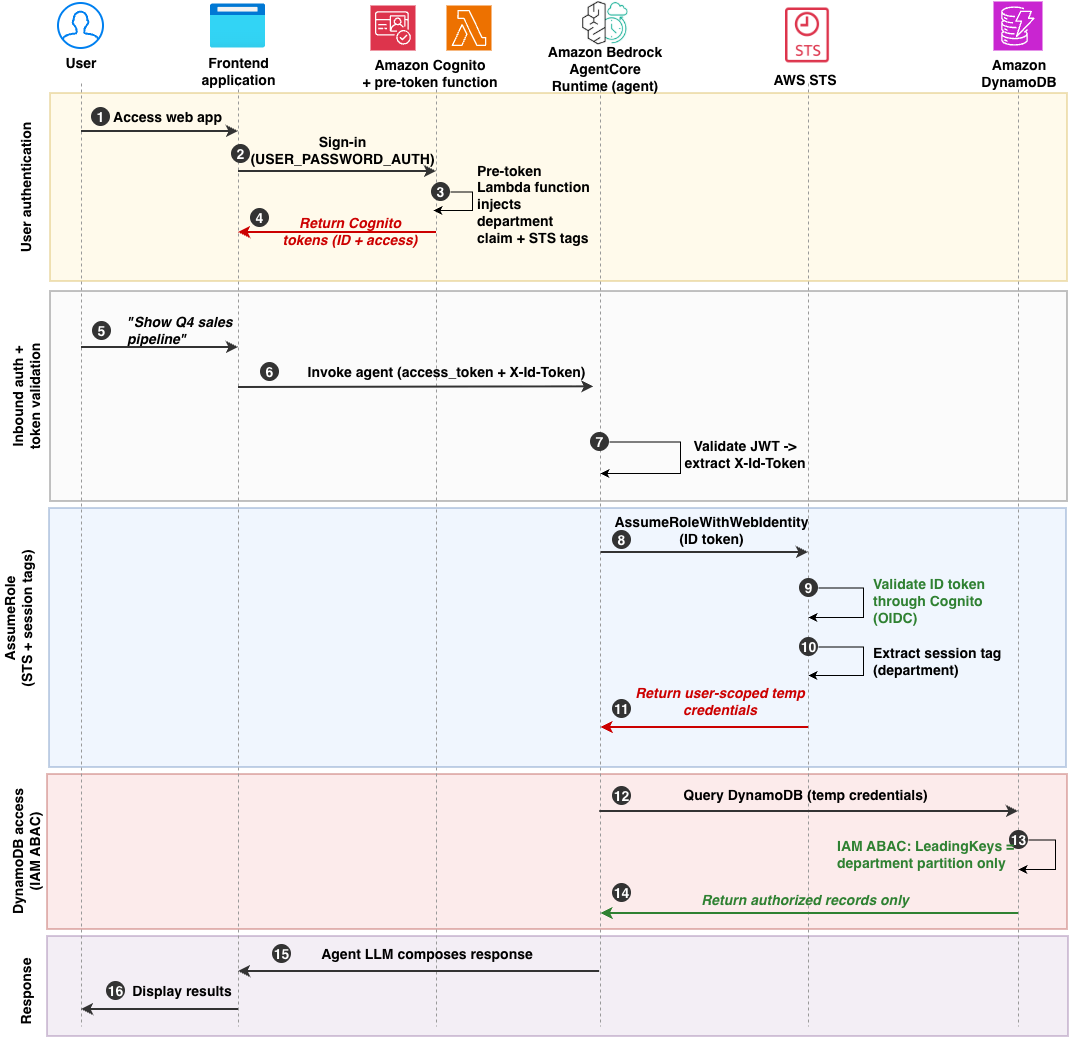
For DynamoDB access, you can use AssumeRoleWithWebIdentity with session tags to create per-request, user-scoped credentials rather than granting the agent a static IAM role with direct table access. The agent passes the user’s signed ID token to AWS STS, which extracts the department tag from the token’s https://aws.amazon.com/tags claim and returns temporary credentials constrained to that department’s data partition. This moves access control from agent code to IAM policy evaluation. STS additionally validates the token’s audience (aud) claim against the IAM OIDC provider configuration, preventing tokens issued for other app clients from being used to assume the role. The following diagram shows this flow (Figure 3).
Before this runtime flow can execute, complete the following configuration:
Register Amazon Cognito as an IAM OIDC provider. Although the user authenticates using the Cognito API (USER_PASSWORD_AUTH), STS requires Cognito to be registered as an OIDC provider so it can discover and validate ID tokens. Configure the allowed client IDs (audiences) on the provider to match your application’s app client ID.
Configure the UserScopedDynamoDBRole trust policy to include both sts:AssumeRoleWithWebIdentity and sts:TagSession permissions, with the Amazon Cognito OIDC provider as the federated principal.
By default, AgentCore Runtime drops custom headers as a security measure. To allow the X-Id-Token header through to the agent container, configure it in the agent runtime’s requestHeaderAllowlist so the ID token is forwarded to agent code. The following configuration tells AgentCore Runtime to forward only the X-Id-Token header to agent code, dropping other non-standard headers:
The user authenticates with Amazon Cognito using USER_PASSWORD_AUTH.
The JWT is issued with a custom department claim and the https://aws.amazon.com/tags claim for STS session tagging (covered in the preceding Initial user authentication with IdP section).
Amazon Cognito returns the enriched tokens to the frontend. The access token carries the department claim for inbound authorization. The ID token carries both the department claim and the https://aws.amazon.com/tags claim for downstream STS calls.
The user asks the agent a question (for example, “Show Q4 sales pipeline”).
The frontend calls AgentCore Runtime, passing two tokens: the Amazon Cognito access token in the Authorization header (for inbound authorization), and the user’s ID token as a custom X-Id-Token header (for downstream STS calls).
AgentCore Runtime validates the JWT and verifies the department claim matches the allowed values configured in the inbound authorizer. If validation fails, the request is rejected with HTTP 401 before agent code executes. After validation, AgentCore forwards the request to the agent container along with the allowed X-Id-Token header.
The agent calls sts:AssumeRoleWithWebIdentity with the ID token. This call targets a single shared UserScopedDynamoDBRole. The following is the agent code for this step:
AWS STS validates the token against the Amazon Cognito OIDC provider registered in IAM. STS verifies the token’s cryptographic signature, expiration, issuer, and audience (aud). The aud claim in the ID token must match one of the client IDs configured on the IAM OIDC provider resource. This prevents a valid token issued by the same Cognito user pool but for a different app client from being accepted. Note that the agent’s own execution role has no DynamoDB access and only permits sts:AssumeRoleWithWebIdentity, so even a compromised agent can’t bypass this flow.
Note: Amazon Cognito user pools expose a standard OpenID Connect discovery endpoint, which is what you register as the trusted OIDC provider in IAM, even though the user signs in through the Cognito authentication APIs. When STS validates the token, it checks that the aud claim matches the client ID configured in the IAM OIDC provider. Tokens whose audience doesn’t match are rejected, adding a second control alongside signature and issuer validation.
AWS STS extracts the https://aws.amazon.com/tags claim and creates a session with aws:PrincipalTag/department set. The trust policy’s sts:TagSession permission (configured in the prerequisites) enables this. Without it, STS silently drops the session tags and subsequent access is denied.
AWS STS returns temporary credentials. These credentials are user-scoped and tamper-proof because the session tags are derived from the cryptographically signed JWT, not from agent code.
The agent queries DynamoDB using these credentials.
IAM evaluates the dynamodb:LeadingKeys condition against ${aws:PrincipalTag/department}. Only the user’s department partition is accessible. Because IAM evaluates this condition at the policy level, even if agent code is manipulated using prompt injection, cross-department access is denied. The following is an example of the permission policy on the role:
DynamoDB returns only the records from the user’s authorized department partition. Cross-department data is never returned because the IAM policy blocks the API call itself. It doesn’t rely on post-query filtering.
The agent receives the authorized results and passes them to the LLM for natural language response composition.
The composed response is returned to the frontend application and displayed to the user.
Pattern 2: User-scoped authorization to Amazon Bedrock Knowledge Bases
For documents stored in Amazon Bedrock Knowledge Bases, the agent applies metadata filtering at query time. Each document is tagged with a Department metadata attribute during ingestion. Amazon Bedrock Knowledge Bases using metadata filtering to implement the data authorization. You need to provide metadata files alongside the source data files with the same name as the source data file and .metadata.json suffix while uploading data in Amazon S3. Amazon Bedrock Knowledge Bases ingests these documents along with corresponding metadata file. The metadata attributes are stored alongside the vectors as filterable fields in the index.
Each metadata file contains a simple JSON structure with the department attribute. The following example shows the complete content of a metadata file for Sales department documents:
{"metadataAttributes": {"Department": “Sales"}}
When the agent queries Amazon Bedrock Knowledge Bases, it calls the bedrock:Retrieve action and appends the retrievalConfiguration filter scoped to the user’s department. The department value is extracted from the JWT access token that the agent received during inbound authorization.
Note: Metadata filtering is application-layer enforcement. The bedrock:Retrieve API doesn’t expose metadata filter content as an IAM condition key. For stricter isolation, consider separate knowledge bases per department with IAM resource-level policies.
Pattern 3: User-scoped access to external services using on-behalf-of token exchange
We use Salesforce as an example of an external service integration. The same on-behalf-of (OBO) token exchange pattern applies to external service that supports RFC 8693 or a compatible token exchange mechanism. External services like Salesforce don’t support IAM-based access control, so you need a different mechanism to propagate user identity. The AgentCore Identity OBO token exchange (RFC 8693) provides this by exchanging the user’s authenticated identity for a user-scoped token that the external service will recognize and enforce natively.
AgentCore Identity supports three OAuth patterns for external service access. With client credentials—Two-Legged OAuth (2LO) or machine-to-machine (M2M)—the agent authenticates as a service account and receives a token with broad access. The agent is then responsible for filtering data in queries, which makes this pattern suitable when accessing organization-wide data that isn’t scoped to an individual user. A variation of this pattern embeds user context as custom claims within the agent’s M2M token itself, see Empower AI agents with user context using Amazon Cognito. With Authorization Code (3LO), the user explicitly consents through a browser redirect and the external service enforces per-user access. This works when per-service consent is required, but it demands user interaction during the flow, making it impractical for background agent operations. Learn more about this in Secure AI agents with Amazon Bedrock AgentCore Identity on Amazon ECS. With OBO token exchange, the user’s already-authenticated identity is exchanged for a service-scoped token without any additional user interaction, and the external service enforces access.
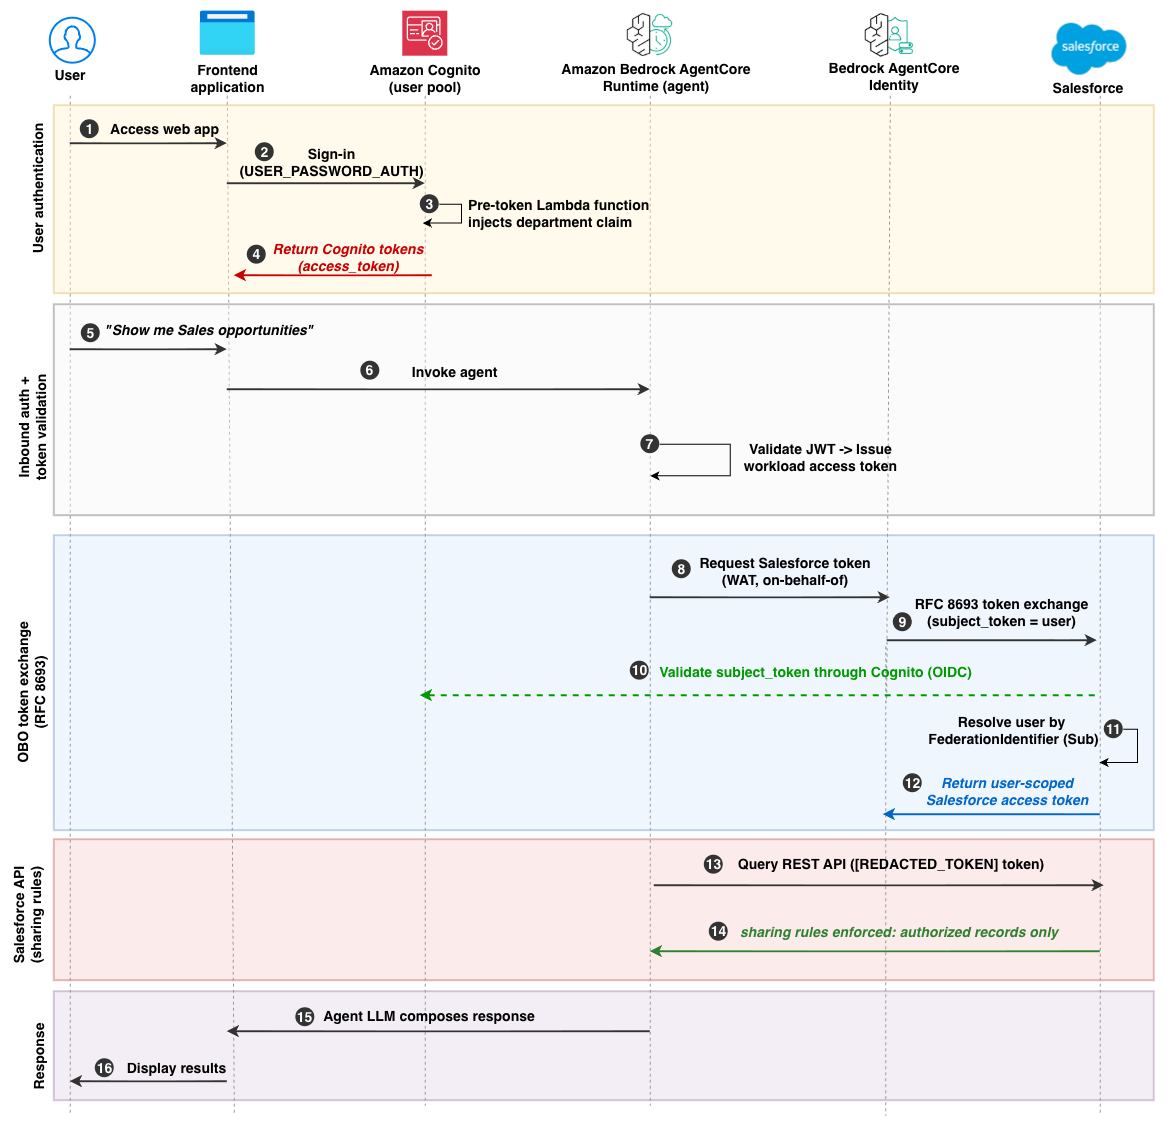
For this use case, OBO is the most appropriate pattern. The user has already authenticated at the entry point (through the IdP), and the agent needs to act on their behalf across multiple services without prompting for additional consent. OBO propagates user identity end-to-end without the agent holding credentials, scales automatically with no per-user token storage, and allows downstream services to enforce their own authorization (sharing rules, role-based access control (RBAC)). Because no browser redirect is needed, OBO works seamlessly for background tool calls where the user isn’t present in a browser session. Figure 4 demonstrates the complete flow when using OBO token exchange.
The user authenticates with Amazon Cognito using USER_PASSWORD_AUTH.
A pre token generation Lambda function injects the custom department claim into the token (covered in the preceding Initial user authentication with IdP section).
Amazon Cognito returns the tokens to the frontend. The access token is issued with the department claim.
The user asks the agent a question (for example, “Show me Sales opportunities”).
The frontend calls AgentCore Runtime with a single agent Amazon Resource Name (ARN), passing the Amazon Cognito access token: POST /invocations, Authorization: Bearer {access_token}.
AgentCore Runtime validates the inbound JWT (signature, expiration, issuer, and custom claims including the department claim). After successful validation, AgentCore Runtime extracts the user identity from the JWT and calls the GetWorkloadAccessTokenForJWT API to exchange it for a workload access token. The agent code receives the workload access token through the invocation payload header. Workload access tokens are exclusively for accessing Amazon Bedrock AgentCore services and can’t be used directly for external services.
The agent calls AgentCore Identity (GetResourceOauth2Token) with the workload access token, requesting a Salesforce token through the configured OBO (on-behalf-of) credential provider. AgentCore Identity validates the caller identity and agent identity, then accesses the stored client credentials from Secrets Manager. If a previously stored OAuth access token has expired, AgentCore Identity automatically obtains a new one using the client credentials, reducing the need for manual token lifecycle management in agent code. The agent code uses the @requires_access_token decorator to invoke this flow:
On the AWS side, this requires an AgentCore Identity OAuth Client configured with Grant type: Token Exchange, Actor token: None, pointing to the Salesforce token endpoint. The Salesforce Connected App consumer secret is stored in Secrets Manager (the agent doesn’t access it directly).
AgentCore Identity performs RFC 8693 token exchange with the Salesforce token endpoint, sending the user identity as the subject_token. AgentCore Identity performs this secure token exchange for user-delegated access based on the configured OAuth 2.0 credential provider. The agent can’t request tokens for arbitrary users because the workload access token cryptographically binds the request to the authenticated user.
Salesforce validates the token against the registered Amazon Cognito auth provider configured in Salesforce Setup.
Salesforce resolves the user using FederationIdentifier. On the Salesforce side, this requires:
Amazon Cognito registered as an OpenID Connect auth provider
A token exchange handler (Apex class extending Auth.Oauth2TokenExchangeHandler) that resolves users by FederationIdentifier
Token exchange flow enabled on the connect app or external client app
Each user’s FederationIdentifier set to their Amazon Cognito subject’s (sub) unique user identifier (UUID).
Sharing rules configured to enforce department-scoped record access
The federation ID (sub) is immutable and can’t be spoofed by the agent, because it originates from the cryptographically signed identity token.
Salesforce returns a user-scoped access token to AgentCore Identity, which passes it back to the agent.
Agent calls the Salesforce REST API using the user-scoped token. No department filtering is needed in the Salesforce Object Query Language (SOQL) query because Salesforce enforces access through sharing rules:
@tool
def query_salesforce_opportunities(query_text: str) -> str:
    access_token = _get_salesforce_token_sync()

    # No department filter needed. Salesforce sharing rules enforce access.
    soql = "SELECT Id, Name, Amount, StageName, CloseDate FROM Opportunity ORDER BY CloseDate DESC LIMIT 10"

    response = requests.get(
        f"{SALESFORCE_URL}/services/data/v59.0/query?q={urllib.parse.quote(soql)}",
        headers={"Authorization": f"Bearer {access_token}"},
        timeout=30,
    )
    return json.dumps(response.json().get("records", []))
Salesforce applies sharing rules and returns only records the user is authorized to access. The agent doesn’t hold Salesforce credentials (refresh tokens, client secrets), these remain with AgentCore Identity.
The agent’s LLM composes a response from the returned records.
The frontend displays the results to the user.
Conclusion
In this post, you learned how to enforce consistent, end-to-end authorization in agentic AI applications by propagating user context from Amazon Cognito through Amazon Bedrock AgentCore to downstream resources. We showed you three patterns:
Per-request user-scoped credentials using AssumeRoleWithWebIdentity with session tags, evaluated by IAM attribute-based access control (ABAC) policies to access Amazon DynamoDB
Department-scoped metadata filtering at the application layer to access Amazon Bedrock Knowledge Bases.
On-behalf-of token exchange (RFC 8693) using AgentCore Identity, with Salesforce-native sharing rules governing access to external CRM data.
The key takeaway is that the agent coordinates work but doesn’t decide who can access what. Access decisions are made by infrastructure-level controls and the downstream service’s authorization model. This layered approach means that even if the agent behaves unexpectedly, unauthorized data access is still blocked.
You can use this as a reference implementation and adapt it to your requirements by choosing authorization attributes relevant to your organization (such as department, role, business unit, or region), integrating additional data sources, or extending the token exchange patterns to other external services.
On August 19, 2026, a security advisory was published for CVE-2026-19490, a critical authentication bypass vulnerability affecting Citrix NetScaler ADC and NetScaler Gateway. The vulnerability carries a CVSS v4.0 base score of 9.3 and can be exploited remotely by an unauthenticated attacker over the network without user interaction or elevated privileges.
NetScaler ADC and NetScaler Gateway are widely deployed enterprise networking products commonly positioned at or near the network perimeter. NetScaler ADC provides application delivery, traffic management, load balancing, SSL/TLS offloading, and application security capabilities, while NetScaler Gateway provides secure remote access and VPN functionality. Because these systems are frequently deployed in enterprise DMZs and exposed to the public internet, authentication bypass vulnerabilities affecting Citrix products are nearly always exploited by threat actors.
NetScaler ADC and NetScaler Gateway 14.1: Versions prior to 14.1-73.32
NetScaler ADC and NetScaler Gateway 13.1: Versions prior to 13.1-63.21
NetScaler ADC FIPS: Versions prior to 14.1-73.32 FIPS
NetScaler ADC FIPS and NDcPP: Versions prior to 13.1-37.277
As of August 19, 2026, Rapid7 has not observed evidence that CVE-2026-19490 is being exploited in the wild. However, organizations should prioritize patching affected systems on an emergency basis, since Citrix products are high-value targets that tend to quickly see exploitation in the wild.
Mitigation guidance
Organizations running affected NetScaler ADC or NetScaler Gateway appliances should review the official NetScaler advisory and apply the required updates to affected systems on an emergency basis.
Fixed versions for affected products are listed below:
NetScaler ADC and NetScaler Gateway 14.1-73.32 and later releases
NetScaler ADC and NetScaler Gateway 13.1-63.21 and later releases of 13.1
NetScaler ADC 14.1-FIPS 14.1-73.32 FIPS and later releases of 14.1-FIPS
NetScaler ADC 13.1-FIPS and 13.1-NDcPP 13.1-37.277 and later releases of 13.1-FIPS and 13.1-NDcPP
According to Citrix, customers can determine whether affected systems are vulnerable to CVE-2026-19490 by inspecting their NetScaler configuration for the following configuration entries. If one or more of the following items are present, and if the systems are running affected versions, the system is likely to be exploitable:
SAML action configuration is in place:
“add authentication samlAction.*”
Auth or VPN vserver is configured:
“add authentication vserver .*”
“add vpn vserver .*”
For the latest guidance, please refer to the official Citrix advisory.
Rapid7 customers
Exposure Command, InsightVM, and Nexpose
Customers can assess exposure to CVE-2026-19490 on Citrix NetScaler ADC and Gateway using a vulnerability check expected to be available in the August 20 content release.
In 2021, we assessed remote Spectre attacks against Cloudflare Workers. Based on the results, we shipped a production defense called Dynamic Process Isolation (DyPrIs), which identifies maliciously looking scripts and isolates them into separate processes. Since then, newer techniques in the area of stabilizing Spectre attacks have been discovered. To understand if these techniques posed a threat to our Workers production environment, we decided to internally reassess the remote Spectre attack. Building an updated proof-of-concept on the production environment allowed us to empirically assess the risk of Spectre attacks under production workloads.
To mount a successful side-channel attack in production, an external attacker has to overcome additional obstacles such as activity on shared hardware resources, interrupts, context switches, and coarse-grained timers. Our research uncovered a limitation in the implementation of DyPrIs and we managed to demonstrate a remote Spectre attack reliably leaking up to 12 bit/s with a 99% accuracy in the production environment of Cloudflare Workers. As a consequence of this research, we improved DyPrIs, integrated the V8 Sandbox and an in-process isolation mechanism to further reduce the risk of memory disclosure attacks.
Today we are publishing a paper describing our findings, co-authored by Albert Pedersen, Haocheng Xiao, Sam Ainsworth, Nigel Topham, and Martin Schwarzl. This paper covers research done in 2024 and early 2025.
Note that the presented attack is mitigated already in the production system due to countermeasures applied by Cloudflare Workers Runtime team. We did not find any indicators of active exploitation over the last three years.
Cloudflare Workers security model
Cloudflare Workers runs untrusted JavaScript on the edge. Leveraging language-level isolation, in the form of V8 isolates, tens of thousands of tenants can share the same operating-system process. Each Worker has its own separate JavaScript heap. This design keeps startup latency low and lets us run many tenants very efficiently compared to full process isolation. Around the runtime we have multiple layers of defense such as automated V8 patch pipelines, a two-layered sandbox consisting of Linux namespaces and seccomp filters, Cap’n Proto RPC, and the possibility to schedule certain scripts in separate process sandboxes. Still, a single arbitrary read vulnerability within a Worker process can lead to cross-tenant leakage. One vulnerability that is very hard to mitigate exploits the nature of speculative execution, namely in-process Spectre.
Spectre
You can think of speculative execution in terms of hiking. At some point you arrive at a branch and have to predict where to go. If the prediction was correct, you saved some time and could enjoy the sun and a refreshing drink at a mountain hut. However, if you speculate in the wrong direction, you have to turn back. The trail looks untouched, but your footsteps remain in the mud.
Speculative execution in CPUs works similarly. The branch prediction performs an educated guess about a branch’s outcome ahead of time and the CPU speculatively executes it. If the prediction was correct, speculative execution saved some time. However, if the prediction is incorrect, the CPU has to discard the results, roll back and execute the other branch. Because these speculatively executed instructions only exist temporarily in the CPU pipeline and are never permanently retired or committed, the literature refers to them as transient instructions and generalizes the concept as transient execution.
However, due to the transient execution, there are still some traces left in the microarchitectural state for instance in CPU caches. Thus, an attacker can use Spectre to transiently access memory out of bounds, encode a single bit of information into the cache state and exploit the latency of reaccessing data to infer whether the bit was set or not.
To mitigate against in-process Spectre attacks, Cloudflare Workers freezes local timers, disallows multithreading and shared memory and actively detects, periodically shuffles memory and isolates malicious-looking scripts into separate processes.
Attack primitives
The Cloudflare Workers platform deliberately restricts timers. During CPU-only execution, time is effectively frozen. Date.now() and performance.now() do not provide a continuously advancing high-resolution clock. There is no shared memory and no multithreading, so the classic counter-thread timer via a SharedArrayBuffer is not available.
To successfully mount an attack, several challenges have to be solved. First, Workers runtime is limited and co-location between an attacker and victim has to be guaranteed. Second, a reliable, ideally co-located, remote timer has to be discovered, which allows stable timing measurements. Third, the attack runs under production conditions, meaning it requires additional stability measures such as a reliable Spectre gadget enabling transient 64-bit out-of-bounds accesses, robust signal amplification to deal with systems and networking noise, and a primitive to reliably evict data out of the cache.
Spectre gadget
Speculative type confusion Spectre gadget
With the right Spectre gadget (snippet above), an attacker can transiently access out-of-bounds memory and encode a single bit into the cache (probeArray). The attacker then measures the memory access latency to confirm whether data has been cached or not. A faster access means the line was cached and the bit was 1. Conversely, a slower access means it was uncached and the bit was 0. In our attack, we use two different Spectre gadget types. The first one leaks compressed heap pointers, e.g., the isolate’s heap base address (root), and the other one leverages a speculative type confusion to leak from an arbitrary, attacker-crafted userspace 64-bit pointer. At the time of performing the research, the V8 Sandbox was not yet implemented at Cloudflare Workers. Under pointer compression, most objects use 32-bit compressed pointers. TypedArray was one of the few exceptions that still stored a raw 64-bit pointer to its backing store, which is exactly what our gadget abuses.
The branch obj instanceof ObjP performs a type check, i.e., a branch. To mistrain the branch prediction, we call the gadget many times on real ObjP instances, then call it on a different object with an attacker-controlled memory layout ObjI. The CPU speculates on the taken branches and follows obj.ptr[0], even though the object has a different type. To leak a single bit, we mask out one bit and use it to select one of two probeArray lines. Whether that line is cached encodes the bit.
Exploiting the heap leakage gadget, we map neighboring objects and locate an attacker-controlled array. Our second gadget confuses two large objects that span several cache lines, so the type field lands on a different cache line than the field we read. Evicting the type field opens the speculation window while the target field stays cached, and the transient read follows an attacker-controlled 64-bit value. That turns the leak into an arbitrary-address read. A more thorough description of this technique can be found in the paper.
Local demo of leaking an arbitrary 64-bit address.
Signal amplification
A cache hit and a cache miss differ by a few nanoseconds. Moreover, a remote timer is noisy at the scale of a few microseconds up to a few milliseconds. Therefore, some form of signal amplification is required to differentiate a cache hit from a miss. Stephen Röttger and Artur Janc discovered a way to amplify a single memory access, by exploiting the tree-based pseudo least recently used (PLRU) cache-replacement policy in L1 caches. Tree-based PLRU organizes each cache set as a binary tree whose nodes point to the side used least recently, so the CPU evicts by following those pointers. With the right access pattern, an attacker can keep a target line cached indefinitely by touching its tree neighbor whenever the pointers turn toward the target. Quite elegant, right? Leveraging that behavior, the timing of a single cache event can be arbitrarily amplified such that it leads to a lot of L1 hits (faster) compared to lots of L1 misses in the opposite case.
The figure below illustrates whether a memory address X is cached or not. If it’s not cached, the access pattern leads to a lot of cache hits. If it is present, it occupies one node in the tree, and subsequently four cache lines try to fit into three nodes, which results in a lot of L1 misses.
Remote timer
As long as the signal can be amplified, a noisy remote timer is sufficient to differentiate an encoded bit. For instance, a WebSocket connection to an external server serving high-resolution timestamps is enough. The timer could be hosted at Cloudflare or at a co-located data center to the target data center running the Worker. The Worker asks the remote timer to mark a timestamp for a certain event and compute the delta for another request once the event has stopped.
In the paper, we evaluated several different timer setups and were able to reliably achieve sub-ms resolutions on the Median with only a handful of samples even over larger topological distances. The figure below shows an amplified cache event using the tree-based PLRU amplification.
Repeatable measurements
A single measurement is not enough to differentiate timing-encoded data reliably. Production machines are noisy, thus an attacker has to repeat each measurement at least a few times and use some statistical discriminator. Repeating a measurement in our case means resetting the cache state. Two things have to be uncached before each round. The value the speculative branch depends on has to be evicted, so branch resolution stalls long enough to open a speculation window. The probe line that encodes the leaked bit has to be evicted, so the next transient access can re-cache it.
Since there is no direct instruction available in JavaScript, the classic way to do this is to build an eviction set. An eviction set is a group of addresses that map to the same cache set as the target. Accessing them in the right pattern pushes the target out of the cache. In their attack, Stephen Röttger and Artur Janc used an eviction list to reliably evict at least into the L2 cache. This works, but it is expensive. Constructing a precise eviction set requires many timed measurements, and our timer is a noisy remote timer. The previous remote attack against Workers sidestepped the search by traversing an array larger than the L1 and L2 caches on every round. That is an option, but even slower.
Dougall Johnson described a more elegant way in his really cool blog post on portable JavaScript Spectre exploitation. The idea follows directly from the pigeonhole principle. If you allocate far more data than the cache can hold, a randomly chosen cache line is almost certainly not cached. For a 256 KB L2 cache, allocating 64 MB leaves at most a 1/256 chance that a random cache line is still in L2. So instead of evicting a specific line, you never evict at all. You pick a fresh random location that is already evicted with overwhelming probability. The cool side effect of looping frequently over that array of objects is that this will lead to an auto-eviction effect.
To leverage this in JavaScript, we allocate a large pool of attacker and victim object pairs that exceeds the last-level cache. Each measurement round selects a fresh random pair. The object's map pointer, the hidden-class descriptor that the speculative type check reads, is therefore almost certainly already evicted.
Co-locating the attacker and victim isolate
For the attack to work, both the attacker and victim isolate must be scheduled in the same process on the same edge server. One might intuitively think this would be difficult, considering Cloudflare operates tens of thousands of edge servers, but this is in fact quite trivial on Cloudflare Workers. Because Cloudflare Workers are designed to execute on any Cloudflare edge server, invoking the victim script from the attacker script with a fetch(“https://victim.example”) will in most cases cause the scheduler to spin up an instance of the victim worker in the exact same process. The victim isolate can be kept alive by repeatedly making subrequests to it at a certain interval.
What is more, because the attack stability is highly dependent on the CPU load of the edge server running the worker script, this allows an attacker to strategically run the attack in an off-peak colo (e.g. in an Australian colo during European business hours) where the traffic levels are comparatively low.
Defeating isolate resource limits
The Cloudflare Workers runtime enforces a set of limits on all isolates to protect the platform and prevent abuse. For the purposes of conducting this attack, the relevant limits were 30 seconds of CPU time and 1,000 subrequests per invocation. These limits have since been increased, but the following principles are still relevant.
For a regular Worker, each HTTP request, a fetch event, is a new invocation that resets these limits. The catch is landing sequential requests on the same edge server. Load balancing and shifting network conditions make that unreliable. Durable Objects solve it for us.
Durable Objects are built for real-time coordination between clients, so the runtime treats every incoming WebSocket message as an invocation that resets the CPU time and request limits. The attacker opens a persistent WebSocket to a Durable Object worker and sends regular keep-alive messages. This keeps a single isolate alive and gives us a persistent, bi-directional channel to run the attack over.
One quirk cost us some time. An isolate is single-threaded, so incoming WebSocket messages are only processed when the script hands control back to the event loop. During synchronous code the runtime never sees the keep-alive, so it never resets the CPU time. If the thread stays blocked for more than 30 seconds, the runtime kills the isolate. This puts an upper bound on how much we can amplify in a single synchronous burst. Yielding regularly between bursts lets us keep an isolate alive from five to more than 20 hours.
Putting everything together
The previous attack relied mostly on repetition to amplify a single cache access, and therefore, was slowly leaking 120 bit/h. We combined tree-based PLRU amplification with measurement loops. Each iteration re-creates the cache state and thereby adds more timing difference. If an interrupt destroys the cache state in one iteration, it doesn’t matter, since later iterations cancel it out. This made the signal strong enough to classify bits with a remote WebSocket timer. The overall idea is now to combine.
We demonstrated the full end-to-end attack in the Cloudflare Workers production environment, against Workers we controlled. We first leaked memory from the attacker Worker. From there, we leaked data from a co-located victim Worker where we had intentionally placed a secret.
First, we established co-location between an attacker Worker, a victim Worker we owned, and a remote timer. Durable Objects gave us a long-lived execution context. WebSocket messages gave us a repeatable timing source. The /cdn-cgi/trace endpoint helped us confirm machine placement by looking at the fl value.
Second, we added a calibration step to probe the timer with speculatively reachable values. This step matters because production machines are noisy. Per-invocation calibration lets us classify bits from the relative difference between the zero and one distribution. This last test should lead to two clearly separable distributions.
As a first step, we leaked the isolate root from one Worker and in another Worker we used the speculative type confusion with 64-bit pointers to read from the isolate root.
As an intermediate step, we confirmed 64-bit leakage with the second gadget by reading memory from the vDSO region. The vDSO is a convenient target because it contains human-readable strings such as gettimeofday.
Demo Video leaking data from the JavaScript heap
Finally, we placed a JWT token in the victim Worker and leaked it bitwise. The first byte was the character e, represented as 0b01100101. The figure below shows the per-bit classification for that byte. To classify we use a two-sided test to test for both outcomes. Using a majority vote and a percentile-based threshold, we infer the bit. In production, we achieved a leakage rate of up to 12 bit/s with an accuracy of more than 99%. Note that higher leakage rates are possible with the cost of losing accuracy.
Robustness
Depending on the time of the day, the utilization of a machine increases strongly. This slows down the attack since more data has to be sampled. Still, even with high CPU utilization, the attack is still feasible.
Why was this not detected?
DyPrIs watches hardware performance counters and isolates a script into its own process once it looks like a Spectre attack. Two things kept the attack under the radar. First, DyPrIs isolates a script only after its invocation finishes, and the Durable Object keep-alive trick we used in the attack can run for a few hours up to a day. WebSocket keep-alive messages hold a single invocation open for hours, so the leak completes long before isolation would kick in. Second, DyPrIs normalizes branch mispredictions by the number of iTLB accesses. Our remote timer is one large I/O loop, and that WebSocket traffic inflates iTLB activity. The normalized ratio drops below the detection threshold, so the attack looks like an ordinary I/O-heavy Worker.
What we changed
We focus on the three areas of continued V8 hardening, providing stronger in-process isolation, and improving detection.
V8 sandbox
The V8 memory sandbox's final goal is to remove raw 64-bit pointers from large parts of the JavaScript heap, which reduces the usefulness of many memory-corruption primitives. It also makes the specific speculative type-confusion gadgets in this work harder to reuse, because typed-array backing stores no longer expose the same raw pointer structure.
The V8 sandbox is not a complete Spectre mitigation. While the presented 64-bit leak gadget does not work anymore, there might be other Spectre variants or gadgets exploitable to achieve arbitrary out-of-bounds memory accesses.
Hardware-assisted in-process isolation
In September 2025, we deployed in-process isolation for Workers using Memory Protection Keys (MPK). MPK lets a process divide memory into protection domains and switch access rights cheaply. Workers use it to protect each heap from being accessible to the other isolates within the same process.
This changes the Spectre risk model. Each isolate heap now sits behind a hardware-enforced access boundary. A memory access to a page protected with the wrong key is denied by hardware. This blocks the straightforward cross-isolate heap read that this work relied on.
Unfortunately, MPK is not a complete answer to remediate Spectre, but it strictly reduces the leakage surface. It has limits, including a finite number of hardware domains and the need to manage protection-key state carefully.
Improved DyPrIs
We improved DyPrIs so that long-lived executions and I/O-heavy workloads are handled as first-class security cases. Detection cannot happen only after a script finishes. A Durable Object or a WebSocket-heavy Worker can run long enough that post-execution isolation arrives too late.
We are currently investigating whether remote timing behavior could be added as an additional dimension to DyPrIs. While we cannot eliminate remote communication with attacker-controlled infrastructure, the timing data reveals very interesting exfiltration bit patterns. The better approach is to treat repeated timer-like I/O around compute-heavy sections as part of the behavioral signal, not as background noise.
Acknowledgments
We especially thank Haocheng Xiao from University of Edinburgh and his supervisors, Sam Ainsworth and Nigel Topham, for their contributions to the reliability of Spectre in JavaScript.
Version
0.11 of the Tuba
fediverse client has been released. Notable changes in this release include
support for Mastodon collections
and quotes,
ability to create custom thumbnails for attachments, a new emoji picker, a build
for Android, as well as many other enhancements.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.