Tag Archives: accessibility

Your alt text passes automated checks. That doesn’t mean it’s any good.

Post Syndicated from Taarik Ashenafi original https://github.blog/engineering/user-experience/your-alt-text-passes-automated-checks-that-doesnt-mean-its-any-good/


More than one in four images on the web’s most popular home pages have alt text that’s missing, vague, or copied from adjacent images.

That’s from WebAIM’s 2026 WebAIM Million report, which found that alt text,an HTML attribute containing text describing the content of an image, was missing on 16.2% of images across the top million home pages. Among the images that did have alt text, another 10.8% provided an undescriptive attribute, such as alt="image", a raw filename, or a description duplicated from a neighbor.

While automated tooling reliably flags missing alt text, it isn’t as good at fixing poorly written alt text. Most alt text checkers test whether an accessible name for an image exists, not whether the provided alt text says anything useful about the associated image, and that’s a deliberate design choice: a quality-oriented rule with false positives is a rule teams switch off. So alt="IMG_2847.png" passes. So does the same alt="3/5 stars" on five different star-shaped icons.

We built an alt text plugin for the GitHub Accessibility Scanner to help improve your alt text. This post covers where we drew the line between what a checker can prove and what it can only suspect, why our worst bug turned out to be a layout problem rather than a parsing one, and what changed once we let a model into the loop.

If you’re building automated checks of your own, for accessibility or otherwise, the tradeoffs should transfer.

Proving a string is wrong without seeing the picture

Presence of alt text is an objective fact; the attribute is there or it isn’t. Quality is often a judgment call. A machine can’t prove whether a sentence adequately describes a picture in context from markup.

However, not all quality is subjective. There’s several checks you can perform based on the alt text alone, with no need to consult the image content:

  • The attribute is absent (not empty) or whitespace-only.
  • The alt is a filename, such as hero.png, IMG_2847.jpg.
  • The alt is a placeholder somebody meant to replace, such as TODO, tbd.
  • The alt is one generic word naming the medium instead of the content, such as image, logo, chart.
  • The same alt repeats across adjacent images.

Every one of those is a claim about a string, and that became our dividing line. Five deterministic rules run by default which need no credentials for running AI models or network calls. One opt-in rule calls a model with provided image content and surrounding context, for judgments an alt text string can’t support on its own.

First, we had to determine which images to judge on a scanned webpage. We use Playwright’s role-based locator rather than querySelectorAll('img'), so anything not included in the browser’s accessibility tree drops out, including anything carrying alt="". That last exclusion matters most. An empty alt is the author explicitly saying the image is decorative, and flagging it would punish exactly the behavior you want to encourage.

So, how strict should it be? A quality checker lives or dies on false positives, so we chose closed sets over clever heuristics. The vague-alt rule normalizes a string, then checks it against a curated list of words that carry no information on their own. It fires only on an exact match:

  • alt="image" gets flagged.
  • alt="image of the login screen with the SSO button highlighted" doesn’t.

Rules this literal miss plenty of bad alt text. We took the miss over the false positive, because a reliable checker that developers enable beats one that gets switched off.

Repetition is a layout problem, not a DOM problem

Repeated alt text presented an interesting problem. Picture a row of five star-shaped icons that each say "3/5 stars". A screen reader user hears the same thing five times and learns nothing new from four of them.

Our first version walked the images in document order and flagged any run sharing the same normalized alt. It caught things it shouldn’t have. For example, a footer “GitHub” logo and a header “GitHub” logo might sit next to each other in the extracted list but nowhere near each other on screen, so nobody experiences them as a group.

What matters is where images land on screen, not where they sit in the markup. So the rule now checks page layout, and only extends a run when the gap between two bounding boxes is small compared to the boxes themselves:

const gap = Math.max(horizontalGap, verticalGap) 
const largerDim = Math.max(a.boundingBox.width, a.boundingBox.height, 
                           b.boundingBox.width, b.boundingBox.height) 
return gap > GAP_MULTIPLIER * largerDim

Two details worth noting:

  • The multiplier is a judgment call, not a number we derived from anything. It’s the kind of value you tune against real pages instead of trusting from a spec.
  • When either image has no measurable box, the check fails open and the run continues. A missing finding is invisible; a wrong one isn’t.

Getting a model to act like a reviewer, not a critic

Deterministic rules only need the alt string. Anything smarter needs to know what the page is about, and none of that is tracked by the image element. Whether alt="a smiling person" is fine depends entirely on what surrounds it: on a generic mood shot, it’s probably works. But under a heading where a specific person is named, it doesn’t provide enough detail.

In our optional alt-text-qualitycheck, we extract page context alongside each image: the nearest heading, the page title, any <figcaption>, whether the image sits inside a link or button, and up to 600 characters of nearby prose.

The link signal matters most, because when an image is a link’s only content, its alt becomes the link’s accessible name. The right alt then names the destination instead of describing the picture.

One caution: The plugin only records that an image sits inside a link. We don’t check whether it’s the link’s only content, which is the part that actually turns alt into a link name. So right now both cases look identical to the model.

That context, the alt, and the image go to a vision model through GitHub Models. Our failure modes were rarely the model misreading a picture. They were the model having opinions. Given perfectly good alt text, our first version of the checker would suggest different alt text, because “could this be better?” is a question a language model always answers yes to. Every image becomes a finding, so the signal disappears.

Three changes fixed it:

  • A decision procedure instead of an instruction. The prompt walks four ordered steps, stops at the first that matches, and emits that step’s verdict: decorative, redundant with a caption, functional, or informative.
  • Explicit anti-nitpick rules. Trust the author’s framing. Separate redundant prefixes (“Image of…”) from semantic ones (“Photograph of…”). Treat a short alt as correct when the surrounding prose already analyzes the image.
  • Structured output with a forced field order, so reasoning is generated before verdict and the model has to build an argument before it picks a label.

None of that makes the model unfailingly correct. It makes it consistent enough to iterate against. The repository carries an offline grading harness built from published teaching material: WebAIM, the W3C images tutorial, and POET. The rule and the harness share one prompt, so what you tune offline is what runs in CI. That harness only tests the model’s judgment, though, not the whole pipeline. A case can score perfectly there and never reach the model in a real scan.

Sending images to a model is a privacy and cost decision

The moment a check calls an external model with webpage data, it stops being just a lint rule and requires careful data flow design. A few things follow from that:

  • The rule is off by default. It won’t run unless you deliberately enable it in your plugin configuration, and it needs a token with access to GitHub Models.
  • URLs get redacted. Image URLs and link hrefs often carry signed CDN tokens or session identifiers, so query and fragment are stripped from anything entering the model context or the rule’s error logs. For the same reason, src and srcset are replaced with (omitted) in the markup we send.
  • Everything in that context window is untrusted input. Titles, headings, and prose all come from the page being scanned, and a page can contain text written to steer a model. Structured output constrains the shape of a response, not the reasoning behind it.

One caution, because that list is easy to over-read: findings still carry the real page URL and original HTML into the scanner’s normal reporting pipeline. That’s on purpose, since you can’t fix an image you can’t locate. Redaction narrows what reaches the model and the logs, not what lands in your own issues. And if you set up Azure AI Vision credentials, an optional OCR pre-pass sends image bytes to a second place. Nothing requires Azure, but a data-flow review needs to cover both paths.

Cost follows the same shape. In the common case this is one model call per image per scan, which on an image-heavy site dominates the cost of the whole run. That’s reason enough to put it on a schedule rather than on every commit.

What this still can’t do

  • The deterministic rules are literal. They catch alt text that’s obviously unwritten, not alt text that’s fluent and wrong. They also read the alt attribute rather than the computed accessible name, so an aria-label that fixes the problem won’t stop the finding.
  • The model-backed rule produces false positives. Every finding is a prompt for human attention, not a verdict.
  • Silence isn’t coverage. That rule re-fetches images outside the browser session, so anything behind authentication can fail to load. Fetch and model errors are logged and skipped, which means a page can come back clean because nothing got checked.
  • Suggested alt text is a draft. A model that sees the image and a few nearby words can’t account for your audience, your house style, or the job that image is doing on the whole page.
  • Some findings double up with the scanner’s built-in checks, since our missing-alt rule covers the same ground.
  • We only check HTML <img> tags. SVG, role="img" containers, CSS backgrounds, and canvas aren’t covered yet.
  • This is new code with limited real-world feedback. Rules like these improve when they meet the variety of markup and content found across real sites. This plugin hasn’t had that yet, so treat early findings accordingly.
  • Passing isn’t conformance. Automated checks are a floor. Testing with people who use assistive tech is the goal.

What we’d tell you if you’re building something similar

Separate what you can prove from what you can only suspect, and give them different defaults. Checks that prove something should be cheap, predictable, and on by default. Checks that only suspect something should be opt-in, and should read as a suggestion rather than a verdict. Then, ask what the user experiences rather than what the DOM says. Every gap still open in this plugin has that second shape. We record that an image is inside a link, not that it is the link. We read an attribute, not a computed name.

That distance is the real boundary, and a better model doesn’t close it. Deciding what the functionality of an image is for a user who can’t see it still requires human judgment. What automation buys you is making sure that human is giving the right images a second examination.

Try the alt-text plugin in your accessibility scanning workflow. If it tells you the wrong thing, please report it. Open an issue with the finding and, if public, a link to the affected page.

The post Your alt text passes automated checks. That doesn’t mean it’s any good. appeared first on The GitHub Blog.
Keep coding when your internet drops: Offline support in the Code Editor

Post Syndicated from Greg Annandale original https://www.raspberrypi.org/blog/offline-support-in-the-code-editor/

Our free, browser-based Code Editor now keeps working when your internet connection doesn’t. If your connection breaks in the middle of a lesson or a project, you can carry on writing and running your code without disruption, even if the page is reloaded.

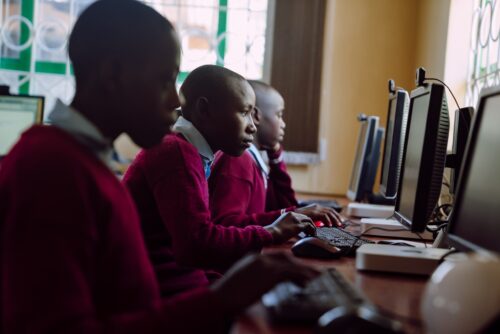
Learners in a classroom in Kenya.

Why we built this

An unstable internet connection is a minor annoyance when you’re reading a web page, but it’s a much bigger problem when you’re 20 minutes into creating a program.

Until now, losing your connection while using the Code Editor could mean losing your work: if you refreshed the page at the wrong moment, you might have seen a blank screen or a browser error instead of your program.

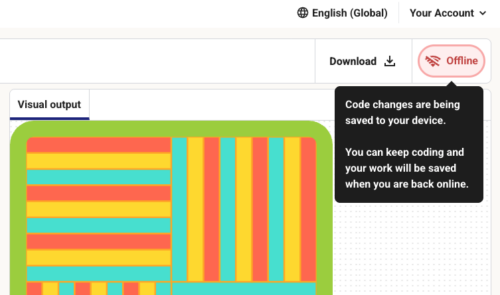
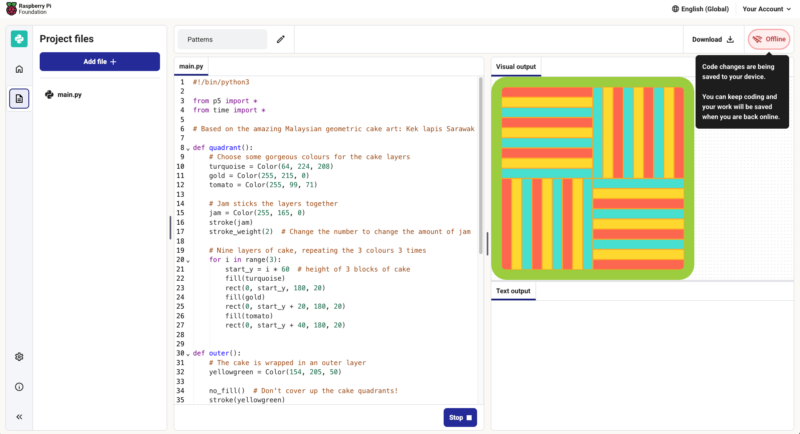
A screenshot of the Code Editor being used without internet connection.
Better offline support means the Code Editor can be more useful for learning and teaching.

When we wanted to understand better what learners and educators around the world need from the Code Editor, we carried out research in countries including India, Kenya, and South Africa. One topic we explored was the availability and reliability of internet connections in metropolitan and rural areas. While it was no surprise that internet access is often slow, unreliable, or expensive in rural areas, we learned that issues related to electricity supply, such as load-shedding and brownouts, are also prevalent in metropolitan areas. All this shapes what is realistically possible in a programming activity using an online editor.

And connectivity issues can occur in any school computing lab where 30 learners are all accessing the same WiFi at once, or for a Code Club running off a mobile hotspot in a community centre, or for someone finishing their homework on patchy mobile data.

That’s why it became a priority for us to improve the Code Editor’s offline support by making it resilient to disconnection.

As we describe in our recently shared draft principles for safe and responsible education technology, one of our commitments is to design for diverse needs, abilities, and contexts — including not to assume constant internet connectivity. This Code Editor update is a small, practical piece of that commitment.

What this means for learners and teachers

The Code Editor was built with resilience in mind from the start, for example running code in your browser rather than on a server, and saving your project locally on your device as you go.

Our recent additions ensure that once you’ve opened the Code Editor while online, your browser holds on to even more of the parts you need to keep coding without a connection. Now if you go offline midway through using the Editor:

  • You’ll see a clear message in the Editor flagging that you’re offline
  • A full page refresh won’t result in a connection error or blank screen
  • If you’re logged in, everything you do in the Editor while offline is saved to your account automatically once you’re back online
  • You can still download your code using the ‘download’ button, in case you know you’re going to be offline for a while and need to save your program file on your computer or a storage device
A screenshot of the message the Code Editor shows when it is being used offline.
A message shows in the Editor when the internet connection is down.

How it works, in brief

This update is built on a service worker, a script your internet browser runs in the background. When you first load the Code Editor, the service worker stores the files the Editor needs in your browser’s cache. If the network connection then breaks, the service worker serves those stored files instead of trying and failing to fetch them. When you come back online, it automatically refreshes the cache so you’re not left running old files.

What is not possible at the moment

The Code Editor isn’t a full offline app that you install. It’s a browser-based app that we have now upgraded to better cope with losing its internet connection, which means:

  • You need to have loaded the Code Editor at least once while online, in the browser and on the device you’re going to use
  • When you go offline, you can’t open projects you haven’t already loaded
  • If you clear your browser data while offline, any changes you’ve made to projects will disappear
  • You can’t log into or out of your account while offline, and saving to your account pauses until you’re back online
  • Any feature that needs the network, such as sharing projects with students in Code Classroom, won’t be available until you reconnect

We’ll keep working to extend what parts of the Editor work offline.

Try it and tell us how you get on

The Code Editor works in your browser with no setup and will always be free for educators and learners. We hope this update makes it more useful for people in lots of different settings.

The update is one of those features some people will never notice, which is rather the point: it should feel like nothing went wrong. If your connection is unreliable and you try out the updated Code Editor, we’d love you to tell us whether or not it works well for you.

We would like to thank Cisco for the generous funding that made this work possible.

The post Keep coding when your internet drops: Offline support in the Code Editor appeared first on Raspberry Pi Foundation.

Continuous AI for accessibility: How GitHub transforms feedback into inclusion

Post Syndicated from Carie Fisher original https://github.blog/ai-and-ml/github-copilot/continuous-ai-for-accessibility-how-github-transforms-feedback-into-inclusion/


For years, accessibility feedback at GitHub didn’t have a clear place to go.

Unlike typical product feedback, accessibility issues don’t belong to any single team—they cut across the entire ecosystem. For example, a screen reader user might report a broken workflow that touches navigation, authentication, and settings. A keyboard-only user might hit a trap in a shared component used across dozens of pages. A low vision user might flag a color contrast issue that affects every surface using a shared design element. No single team owns any of these problems—but every one of them blocks a real person.

These reports require coordination that our existing processes weren’t originally built for. Feedback was often scattered across backlogs, bugs lingered without owners, and users followed up to silence. Improvements were often promised for a mythical “phase two” that rarely materialized.

We knew we needed to change this. But before we could build something better, we had to lay the groundwork—centralizing scattered reports, creating templates, and triaging years of backlog. Only once we had that foundation in place could we ask: How can AI make this easier?

The answer was an internal workflow, powered by GitHub Actions, GitHub Copilot, and GitHub Models, that ensures every piece of user and customer feedback becomes a tracked, prioritized issue. When someone reports an accessibility barrier, their feedback is captured, reviewed, and followed through until it’s addressed. We didn’t want AI to replace human judgment—we wanted it to handle repetitive work so humans could focus on fixing the software.

This is how we went from chaos to a system where every piece of accessibility feedback is tracked, prioritized, and acted on—not eventually, but continuously.

Accessibility as a living system

Continuous AI for accessibility weaves inclusion into the fabric of software development. It’s not a single product or a one-time audit—it’s a living methodology that combines automation, artificial intelligence, and human expertise.

This philosophy connects directly to our support for the 2025 Global Accessibility Awareness Day (GAAD) pledge: strengthening accessibility across the open source ecosystem by ensuring user and customer feedback is routed to the right teams and translated into meaningful platform improvements.

The most important breakthroughs rarely come from code scanners—they come from listening to real people. But listening at scale is hard, which is why we needed technology to help amplify those voices. We built a feedback workflow that functions less like a static ticketing system and more like a dynamic engine—leveraging GitHub products to clarify, structure, and track user and customer feedback, turning it into implementation-ready solutions.

Designing for people first

Before jumping into solutions, we stepped back to understand who this system needed to serve:

  • Issue submitters: Community managers, support agents, and sales reps submit issues on behalf of users and customers. They aren’t always accessibility experts, so they need a system that guides them and teaches accessibility concepts in the flow of work.
  • Accessibility and service teams: Engineers and designers responsible for fixes need structured, actionable data—reproducible steps, WCAG mapping, severity scores, and clear ownership.
  • Program and product managers: Leadership needs visibility into pain points by category, trends, and progress over time to allocate resources strategically.

With these personas in mind, we knew we wanted to 1) treat feedback as data flowing through a pipeline and 2) build a system able to evolve with us.

How feedback flows

With that foundation set, we built an architecture around an event-driven pattern, where each step triggers a GitHub Action that orchestrates what comes next—ensuring consistent handling no matter where the feedback originates. We built this system largely by hand starting in mid-2024. Today, tools like Agentic Workflows let you create GitHub Actions using natural language—meaning this kind of system could be built in a fraction of the time.

The workflow reacts to key events: Issue creation launches GitHub Copilot analysis via the GitHub Models API, status changes initiate hand-offs between teams, and resolution triggers submitter follow-up with the user. Every Action can also be triggered manually or re-run as needed—automation covers the common path, while humans can step in at any point.

Feedback isn’t just captured—it continuously flows through the right channels, providing visibility, structure, and actionability at every stage.

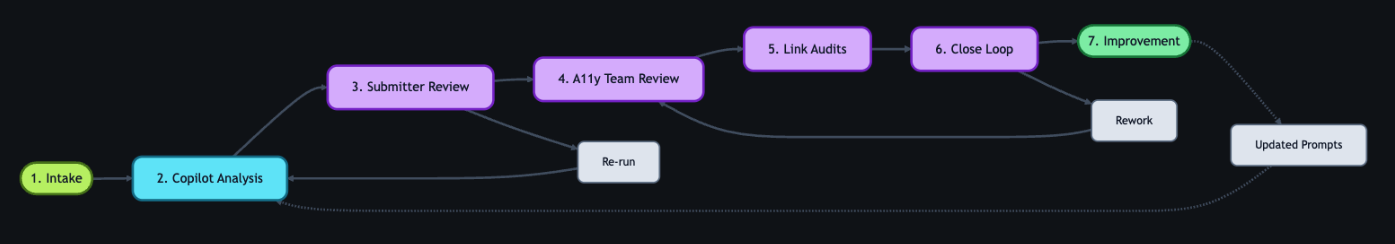
*Click images to enlarge.

A left-to-right flowchart showing the seven steps of the feedback workflow in sequence: Intake, Copilot Analysis, Submitter Review, Accessibility Team Review, Link Audits, Close Loop, and Improvement. Feedback loops show that Submitter Review can re-run Copilot Analysis, Close Loop can return to Accessibility Team Review, and Improvement feeds updated prompts back to Copilot Analysis.

1. Actioning intake

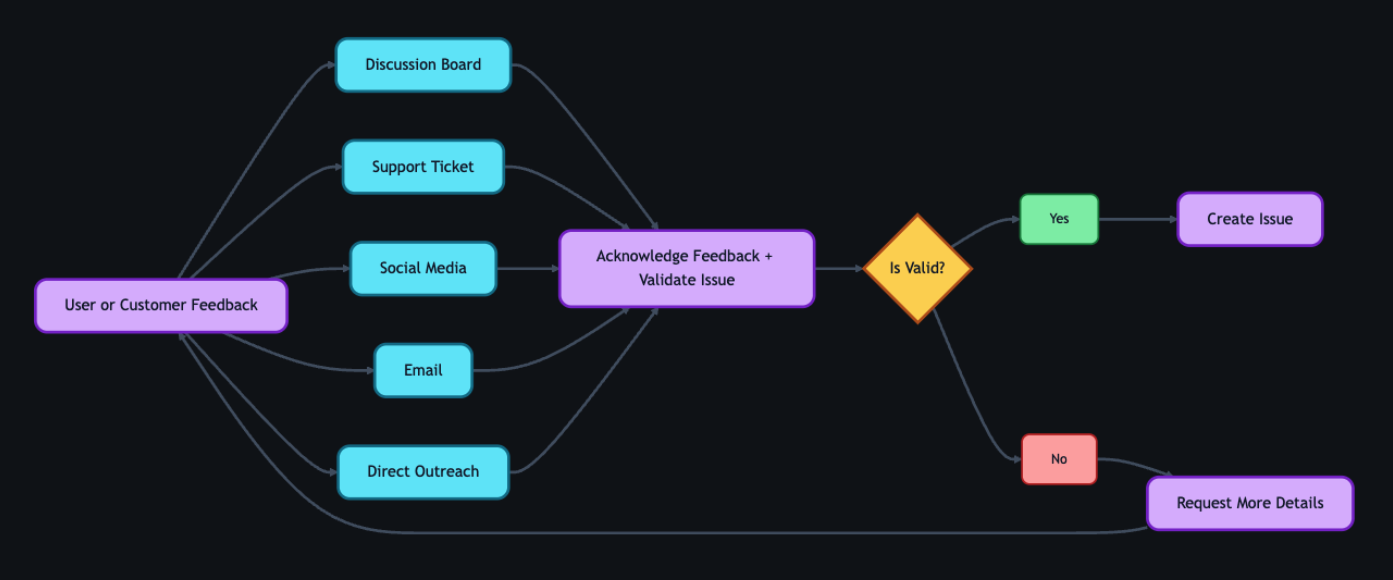
Feedback can come from anywhere—support tickets, social media posts, email, direct outreach—but most users choose the GitHub accessibility discussion board. It’s where they can work together and build community around shared experiences. Today, 90% of the accessibility feedback flows through that single channel. Because posts are public, other users can confirm the problem, add context, or suggest workarounds—so issues often arrive with richer detail than a support ticket ever could. Regardless of the source, every piece of feedback gets acknowledged within five business days, and even feedback we can’t act on gets a response pointing to helpful resources.

When feedback requires action from internal teams, a team member manually creates a tracking issue using our custom accessibility feedback issue template. Issue templates are pre-defined forms that standardize how information is collected when opening a new issue. The template captures the initial context—what the user reported, where it came from, and which components are involved—so nothing is lost between intake and triage.

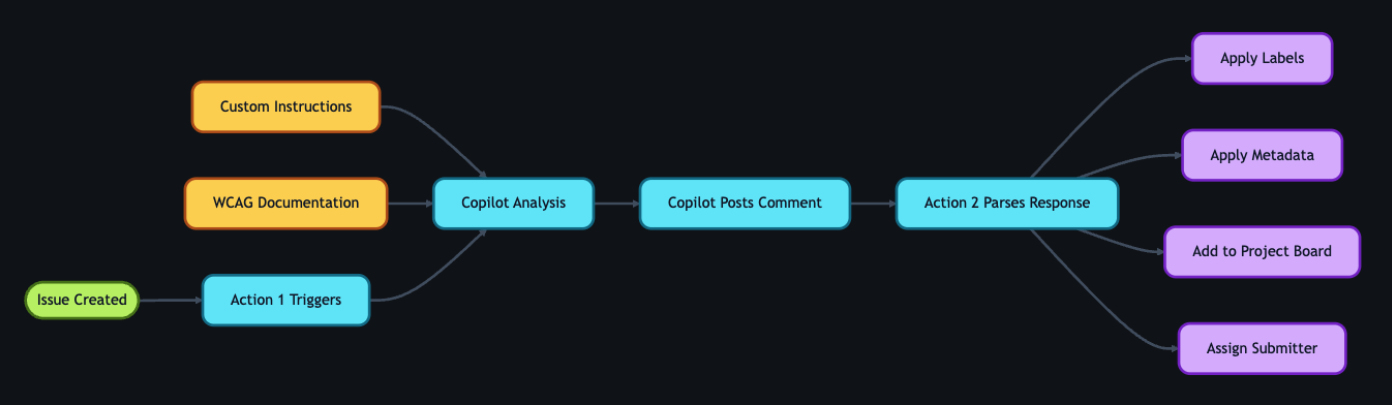
This is where automation kicks in. Creating the issue triggers a GitHub Action that engages GitHub Copilot, and a second Action adds the issue to a project board, providing a centralized view of current status, surfacing trends, and helping identify emerging needs.

A left-to-right flowchart where user or customer feedback enters through Discussion Board, Support Ticket, Social Media, Email, or Direct Outreach, moves to an Acknowledge and Validate step, branches at a validity decision, and either proceeds to Create Issue or loops back through Request More Details to the user.

2. GitHub Copilot analysis

With the tracking issue created, a GitHub Action workflow programmatically calls the GitHub Models API to analyze the report. We chose stored prompts over model fine-tuning so that anyone on the team can update the AI’s behavior through a pull request—no retraining pipeline, no specialized ML knowledge required.

We configured GitHub Copilot using custom instructions developed by our accessibility subject matter experts. Our prompt serves two roles: triage analysis, which classifies issues by WCAG violation, severity, and affected user group, and accessibility coaching, where GitHub Copilot acts as a subject-matter expert to help teams write and review accessible code.

These instruction files point to our accessibility policies, component library, and internal documentation that details how we interpret and apply WCAG success criteria. When our standards evolve, the team updates the markdown and instruction files via pull request—the AI’s behavior changes with the next run, not the next training cycle. For a detailed walkthrough of this approach, see our guide on optimizing GitHub Copilot custom instructions for accessibility.

The automation works in two steps. First, an Action fires on issue creation and triggers GitHub Copilot to analyze the report. GitHub Copilot populates approximately 80% of the issue’s metadata automatically—over 40 data points including issue type, user segment, original source, affected components, and enough context to understand the user’s experience. The remaining 20% requires manual input from the team member. GitHub Copilot then posts a comment on the issue containing:

  • A summary of the problem and user impact
  • Suggested WCAG success criteria for potential violations
  • Severity level (sev1 through sev4, where sev1 is critical)
  • Impacted user groups (screen reader users, keyboard users, low vision users, etc.)
  • Recommended team assignment (design, engineering, or both)
  • A checklist of low-barrier accessibility tests so the submitter can verify the issue

Then a second Action fires on that comment, parses the response, applies labels based on the severity GitHub Copilot assigned, updates the issue’s status on the project board, and assigns it to the submitter for review.

If GitHub Copilot’s analysis seems off, anyone can flag it by opening an issue describing what it got wrong and what it should have said—feeding directly into our continuous improvement process.

A left-to-right flowchart where a newly created issue triggers Action 1, which feeds the report along with custom instructions and WCAG documentation into Copilot Analysis. Copilot posts a comment with its findings, then Action 2 parses that comment and branches into four parallel outcomes: applying labels, applying metadata, adding to the project board, and assigning the submitter.

3. Submitter review

Before we act on GitHub Copilot’s recommendations, two layers of review happen—starting with the issue submitter.

The submitter attempts to replicate the problem the user reported. The checklist GitHub Copilot provides in its comment guides our community managers, support agents, and sales reps through expert-level testing procedures—no accessibility expertise required. Each item includes plain-language explanations, step-by-step instructions, and links to tools and documentation.

Example questions include:

  • Can you navigate the page using only a keyboard? Press “Tab” to move through interactive elements. Can you reach all buttons, links, and form fields? Can you see where your focus is at all times?
  • Do images have descriptive alt text? Right-click an image and select “Inspect” to view the markup. Does the alt attribute describe the image’s purpose, or is it a generic file name?
  • Are interactive elements clearly labeled? Using a screen reader, navigate to a button or link. Is its purpose announced clearly? Alternatively, review the accessibility tree in your browser’s developer tools to inspect how elements are exposed to assistive technologies.

If the submitter can replicate the problem, they mark the issue as reviewed, which triggers the next GitHub Action. If they can’t reproduce it, they reach out to the user for more details. Once new information arrives, the submitter can re-run the GitHub Copilot analysis—either by manually triggering the Action from the Actions tab or by removing and re-adding the relevant label to kick it off automatically. AI provides the draft, but humans provide the verification.

A left-to-right flowchart where the submitter receives the issue with Copilot’s checklist, attempts to replicate the problem, and reaches a decision. If replicable, the issue is marked as reviewed and moves to the accessibility team. If not replicable, the submitter contacts the user for more details. When new information arrives, the submitter re-runs Copilot analysis, which loops back to the replication step.

4. Accessibility team review

Once the submitter marks the issue as reviewed, a GitHub Action updates its status on the workflow project board and adds it to a separate accessibility first responder board. This alerts the accessibility team—engineers, designers, champions, testing vendors, and managers—that GitHub Copilot’s analysis is ready for their review.

The team validates GitHub Copilot’s analysis—checking the severity level, WCAG mapping, and category labels—and corrects anything the AI got wrong. When there’s a discrepancy, we assume the human is correct. We log these corrections and use them to refine the prompt files, improving future accuracy.

Once validated, the team determines the resolution approach:

  • Documentation or settings update: Provide the solution directly to the user.
  • Code fix by the accessibility team: Create a pull request directly.
  • Service team needed: Assign the issue to the appropriate service team and track it through resolution.

With a path forward set, the team marks the issue as triaged. An Action then reassigns it to the submitter, who communicates the plan to the user—letting them know what’s being done and what to expect.

A left-to-right flowchart where a reviewed issue triggers an Action that updates the project board and adds it to the first responder board. The accessibility team validates Copilot’s analysis, logs any corrections, then determines a resolution: provide documentation, create a code fix, or assign to a service team. All three paths converge at marking the issue as triaged, which triggers an Action that reassigns it to the submitter to communicate the plan to the user.

5. Linking to audits

As part of the review process, the team connects user and customer feedback to our formal accessibility audit system.

Roughly 75–80% of the time, reported issues correspond to something we already know about from internal audits. Instead of creating duplicates, we find the existing internal audit issue and add a customer-reported label. This lets us prioritize based on real-world impact—a sev2 issue might technically be less critical than a sev1, but if multiple users are reporting it, we bump up its priority.

If the feedback reveals something new, we create a new audit issue and link it to the tracking issue.

A left-to-right flowchart where the team checks whether an existing audit issue covers the reported problem. If one exists, they link it and add a customer-reported label. If not, they create a new audit issue and link it. Both paths converge at updating priority based on real-world impact.

6. Closing the loop

This is the most critical step for trust. Users who take the time to report accessibility barriers deserve to know their feedback led to action.

Once a resolution path is set, the submitter reaches out to the original user to let them know the plan—what’s being fixed, and what to expect. When the fix ships, the submitter follows up again and asks the user to test it. Because most issues originate from the community discussion board, we post confirmations there for everyone to see.

If the user confirms the fix works, we close the tracking issue. If the fix doesn’t fully address the problem, the submitter gathers more details and the process loops back to the accessibility team review. We don’t close issues until the user confirms the fix works for them.

A left-to-right flowchart where the submitter communicates the resolution plan to the user and monitors until the fix ships. The user is asked to test the fix. If it works, the issue is closed. If it doesn’t, the submitter gathers more details and the process loops back to the accessibility team review.

7. Continuous improvement

The workflow doesn’t end when an issue closes—it feeds back into itself.

When submitters or accessibility team members spot inaccuracies in GitHub Copilot’s output, they open a new issue requesting a review of the results. Every GitHub Copilot analysis comment includes a link to create this issue at the bottom, so the feedback loop is built into the workflow itself. The team reviews the inaccuracy, and the correction becomes a pull request to the custom instruction and prompt files described earlier.

We also automate the integration of new accessibility guidance. A separate GitHub Action scans our internal accessibility guide repository weekly and incorporates changes into GitHub Copilot’s custom instructions automatically.

The goal isn’t perfection—it’s continuous improvement. Each quarter, we review accuracy metrics and refine our instructions. These reviews feed into quarterly and fiscal year reports that track resolution times, WCAG failure patterns, and feedback volume trends—giving leadership visibility into both progress and persistent gaps. The system gets smarter over time, and now we have the data to show it.

A left-to-right flowchart with two parallel loops. In the first, an inaccuracy is spotted, a review issue is opened, the team creates a pull request to update the prompt files, and the changes merge to improve future analyses. In the second, a weekly Action scans the accessibility guide repository and auto-updates Copilot's custom instructions. Both loops feed into quarterly reviews that produce fiscal year reports tracking resolution times, WCAG failure patterns, and feedback volume trends.

Impact in numbers

A year ago, nearly half of accessibility feedback sat unresolved for over 300 days. Today, that backlog isn’t just smaller—it’s gone. And the improvements don’t stop there.

  • 89% of issues now close within 90 days (up from 21%)
  • 62% reduction in average resolution time (118 days → 45 days)
  • 70% reduction in manual administrative time
  • 1,150% increase in issues resolved within 30 days (4 → 50 year-over-year)
  • 50% reduction in critical sev1 issues
  • 100% of issues closed within 60 days in our most recent quarter

We track this through automated weekly and quarterly reports generated by GitHub Actions—surfacing which WCAG criteria fail most often and how resolution times trend over time.

Beyond the numbers

A user named James emailed us to report that the GitHub Copilot CLI was inaccessible. Decorative formatting created noise for screen readers, and interactive elements were impossible to navigate.

A team member created a tracking issue. Within moments, GitHub Copilot analyzed the report—mapping James’s description to specific technical concepts, linking to internal documentation, and providing reproduction steps so the submitter could experience the product exactly as James did.

With that context, the team member realized our engineering team had already shipped accessible CLI updates earlier in the year—James simply wasn’t aware.

They replied immediately. His response? “Thanks for pointing out the –screen-reader mode, which I think will help massively.”

Because the AI workflow identified the problem correctly, we turned a frustration into a resolution in hours.

But the most rewarding result isn’t the speed—it’s the feedback from users. Not just that we responded, but that the fixes actually worked for them:

  • “Huge thanks to the team for updating the contributions graph in the high contrast theme. The addition of borders around the grid edges is a small but meaningful improvement. Keep it up!”
  • “Let’s say you want to create several labels for your GitHub-powered workflow: bug, enhancement, dependency updates… But what if you are blind? Before you had only hex codes randomly thrown at you… now it’s fixed, and those colors have meaningful English names. Well done, GitHub!”
  • “This may not be very professional but I literally just screamed! This fix has actually made my day… Before this I was getting my wife to manage the GitHub issues but now I can actually navigate them by myself! It means a lot that I can now be a bit more independent so thank you again.”

That independence is the point. Every workflow, every automation, every review—it all exists so moments like these are the expectation, not the exception.

The bigger picture

Stories like these remind us why the foundation matters. Design annotations, code scanners, accessibility champions, and testing with people with disabilities—these aren’t replaced by AI. They are what make AI-assisted workflows effective. Without that human foundation, AI is just a faster way to miss the point.

We’re still learning, and the system is still evolving. But every piece of feedback teaches us something, and that knowledge now flows continuously back to our team, our users, and the tools we build. 

If you maintain a repository—whether it’s a massive enterprise project or a weekend open-source library—you can build this kind of system today. Start small. Create an issue template for accessibility. Add a .github/copilot-instructions.md file with your team’s accessibility standards. Let AI handle the triage and formatting so your team can focus on what really matters: writing more inclusive code.

And if you hit an accessibility barrier while using GitHub, please share your feedback. It won’t disappear into a backlog. We’re listening—and now we have the system to follow through.

The post Continuous AI for accessibility: How GitHub transforms feedback into inclusion appeared first on The GitHub Blog.
The most-seen UI on the Internet? Redesigning Turnstile and Challenge Pages

Post Syndicated from Leo Bacevicius original https://blog.cloudflare.com/the-most-seen-ui-on-the-internet-redesigning-turnstile-and-challenge-pages/

You’ve seen it. Maybe you didn’t register it consciously, but you’ve seen it. That little widget asking you to verify you’re human. That full-page security check before accessing a website. If you’ve spent any time on the Internet, you’ve encountered Cloudflare’s Turnstile widget or Challenge Pages — likely more times than you can count.


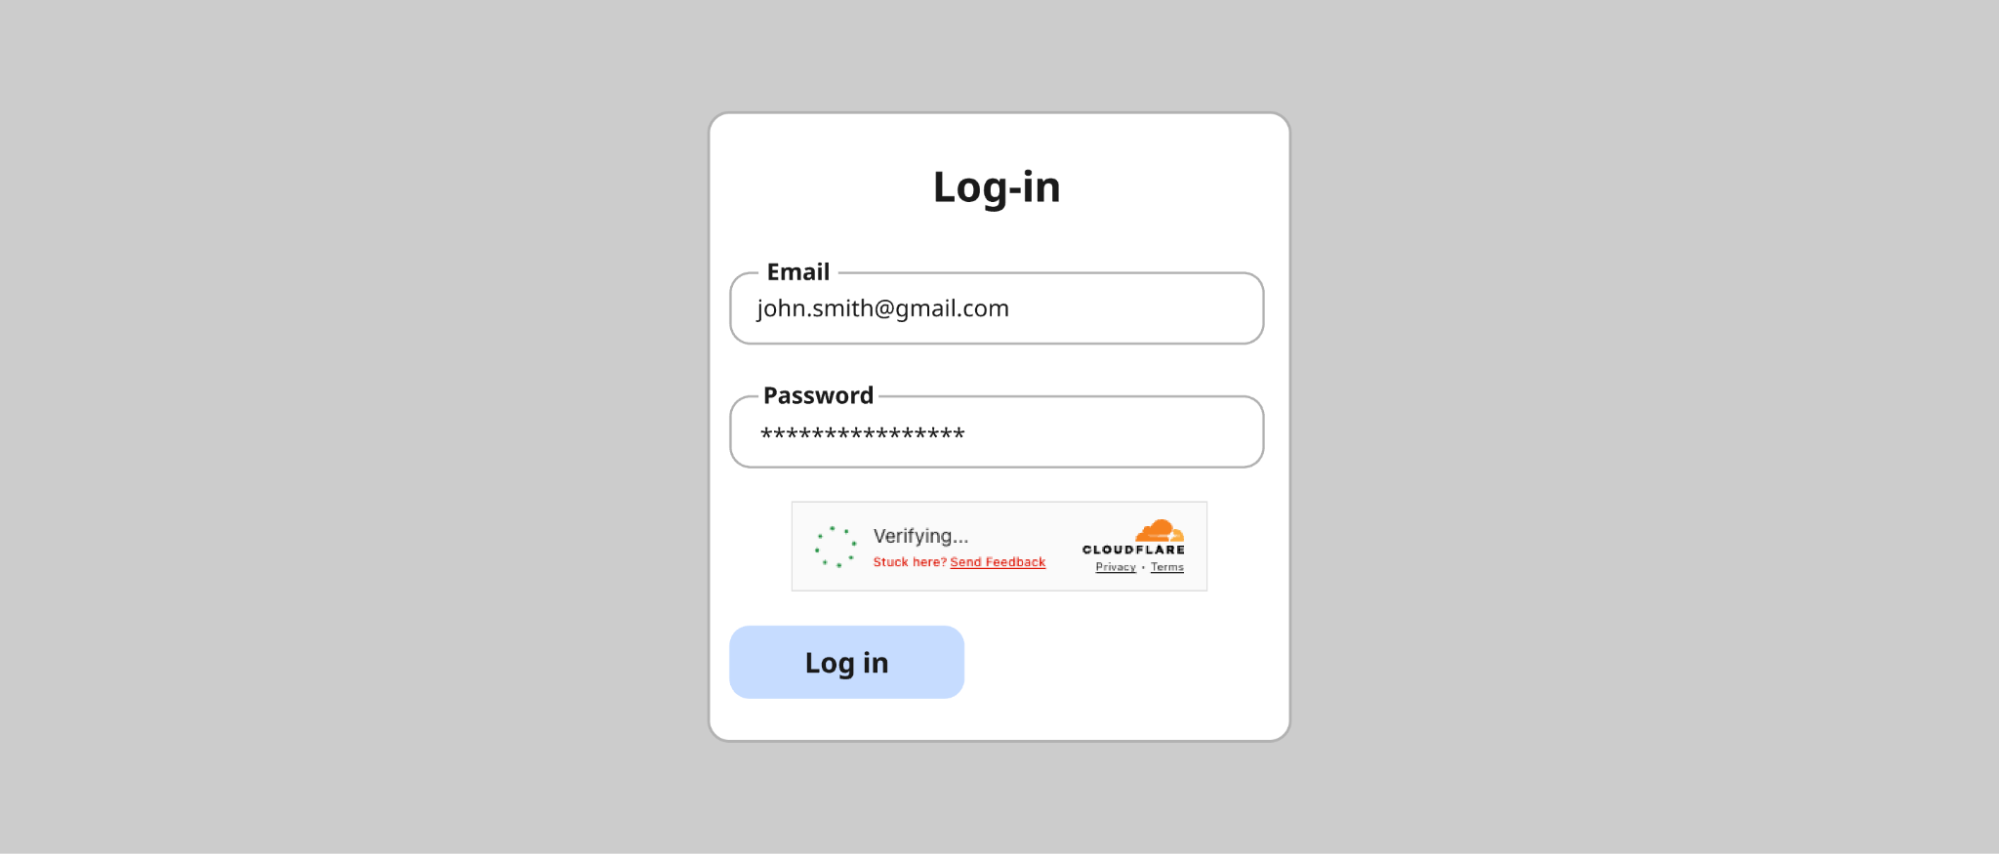
The Turnstile widget – a familiar sight across millions of websites

When we say that a large portion of the Internet sits behind Cloudflare, we mean it. Our Turnstile widget and Challenge Pages are served 7.67 billion times every single day. That’s not a typo. Billions. This might just be the most-seen user interface on the Internet.

And that comes with enormous responsibility.

Designing a product with billions of eyeballs on it isn’t just challenging — it requires a fundamentally different approach. Every pixel, every word, every interaction has to work for someone’s grandmother in rural Japan, a teenager in São Paulo, a visually impaired developer in Berlin, and a busy executive in Lagos. All at the same time. In moments of frustration.

Today we’re sharing the story of how we redesigned Turnstile and Challenge Pages. It’s a story told in three parts, by three of us: the design process and research that shaped our decisions (Leo), the engineering challenge of deploying changes at unprecedented scale (Ana), and the measurable impact on billions of users (Marina).

Let’s start with how we approached the problem from a design perspective.

Part 1: The design process

The problem

Let’s be honest: nobody likes being asked to prove they’re human. You know you’re human. I know I’m human. The only one who doesn’t seem convinced is that little widget standing between you and the website you’re trying to access. At best, it’s a minor inconvenience. At worst? You’ve probably wanted to throw your computer out the window in a fit of rage. We’ve all been there. And no one would blame you.


Turnstile integrated into a login flow

As the world warms up to what appears to be an inevitable AI revolution, the need for security verification is only increasing. At Cloudflare, we’ve seen a significant rise in bot attacks — and in response, organizations are investing more heavily in security measures. That means more challenges being issued to more end users, more often.

The numbers tell the story:

2023: 2.14B daily

2024: 3B daily

2025: 5.35B daily

That’s a 58.1% average increase in security checks, year over year. More security checks mean more opportunities for end user frustration. The more companies integrate these verification systems to protect themselves and their customers, the higher the chance that someone, somewhere, is going to have a bad experience.

We knew it was time to take a hard look at our flagship products and ask ourselves: Are we doing right by the billions of people who encounter these experiences? Are we fulfilling our mission to build a better Internet — not just a more secure one, but a more human one?

The answer, we discovered, was: we could do better.

The design audit

Before redesigning anything, we needed to understand what we were working with. We started by conducting a comprehensive audit of every state, every error message, and every interaction across both Turnstile and Challenge Pages.

What we found wasn’t the best.


The state of inconsistency in the Turnstile widget. Multiple states with no unified approach

The inconsistencies were glaring. We had no unified approach across the multitude of different error scenarios. Some messages were overly verbose and technical (“Your device clock is set to a wrong time or this challenge page was accidentally cached by an intermediary and is no longer available”). Others were too vague to be helpful (“Timed out”). The visual language varied wildly — different layouts, different hierarchies, different tones of voice.

We also examined the feedback we’d received online. Social media, support tickets, community forums — we read it all. The frustration was palpable, and much of it was avoidable.

Take our feedback mechanism, for example. We offered users feedback options like “The widget sometimes fails” versus “The widget fails all the time.” But what’s the difference, really? And how were they supposed to know how often it failed? We were asking users to interpret ambiguous options during their most frustrated moments. The more we left open to interpretation, the less useful the feedback became — and the more frustration we saw across social channels.


The previous feedback screen: “The widget sometimes fails” vs “The widget fails all the time” — what’s the difference?

Our Challenge Pages — the full-page security blocks that appear when we detect suspicious activity or when site owners have heightened security settings — had similar issues. Some states were confusing. Others used too much technical jargon. Many failed to provide actionable guidance when users needed it most.


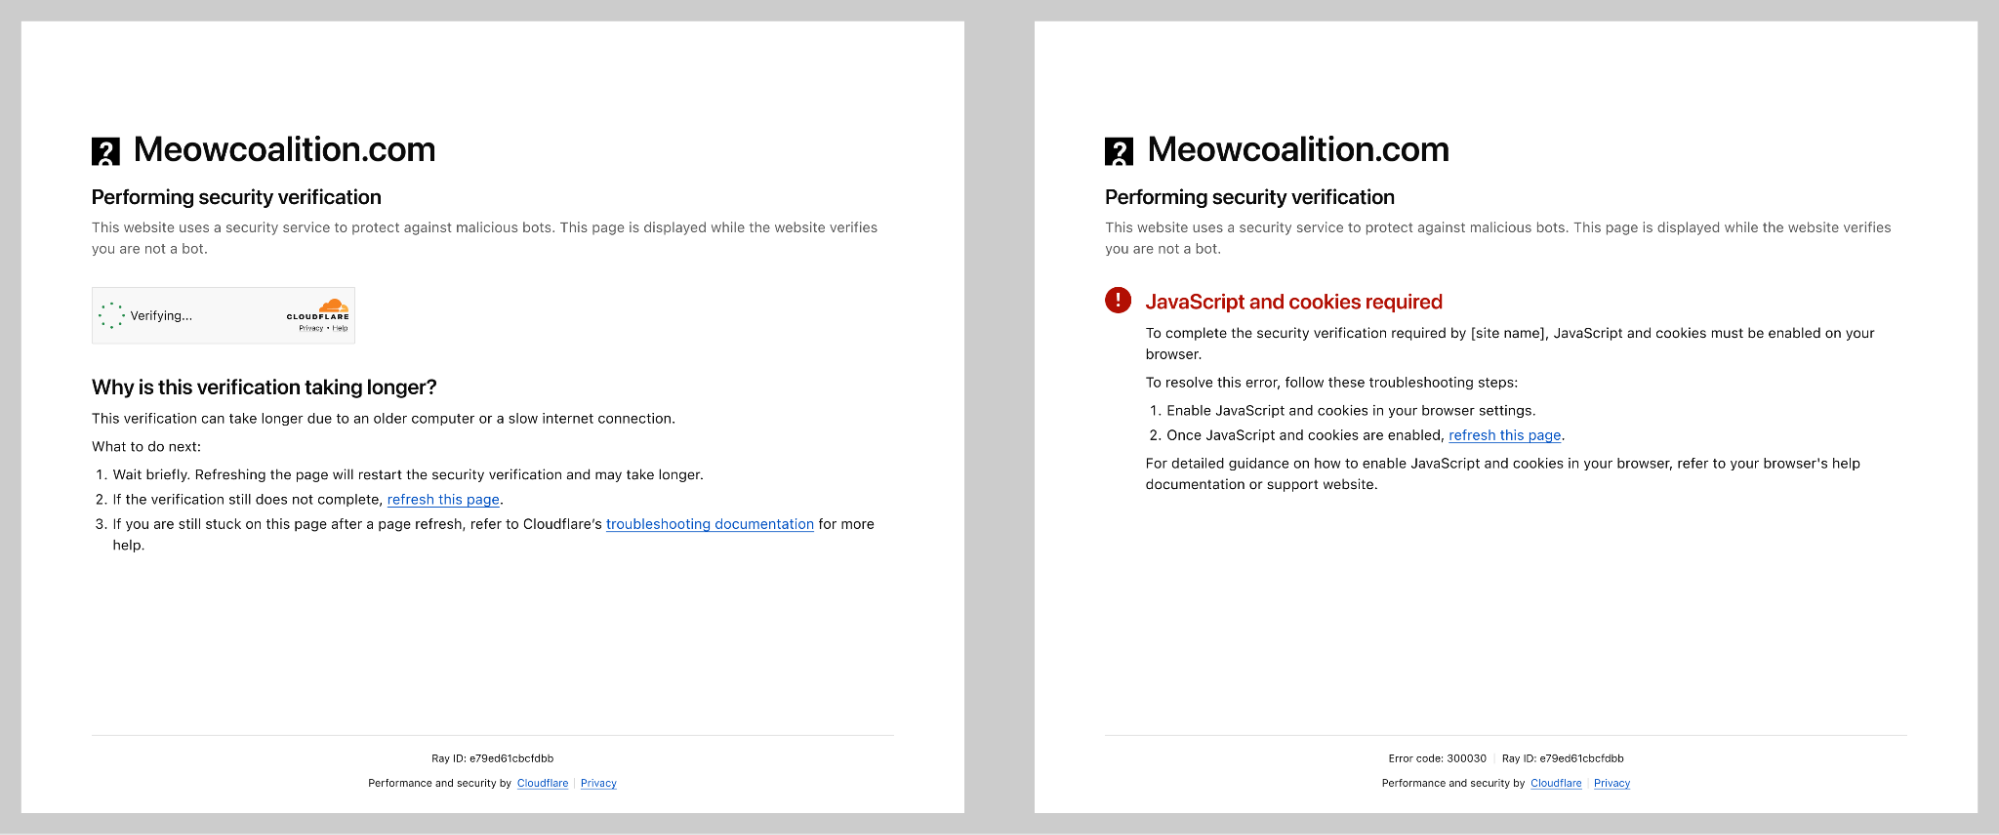
The state of inconsistency on the Challenge pages. Multiple states with no unified approach

The audit was humbling. But it gave us a clear picture of where we needed to focus.

Mapping the user journey

To design better experiences, we first needed to understand every possible path a user could take. What was the happy path? Was there even one? And what were the unhappy paths that led to escalating frustration?


Mapping the complete user journey — from initial encounter through error scenarios, with sentiment tracking

This was a true cross-functional effort. We worked closely with engineers like Ana who knew the technical ins and outs of every edge case, and with Marina on the product side who understood not just how the product worked, but how users felt about it — the love and the hate we’d see online.

We have some of the smartest people working on bot protection at Cloudflare. But intelligence and clarity aren’t the same thing. There’s a delicate balance between technical complexity and user simplicity. Only when these two dance together successfully can we communicate information in a way that actually makes sense to people.

And here’s the thing: the messaging has to work for everyone. A person of any age. Any mental or physical capability. Any cultural background. Any level of technical sophistication. That’s what designing at scale really means — you can’t ignore edge cases, since, at such scale, they are no longer edge cases.

Establishing a unified information architecture

One of the most influential books in UX design is Steve Krug’s Don’t Make Me Think. The core principle is simple: every moment a user spends trying to interpret, understand, or decode your interface is a moment of friction. And friction, especially in moments of frustration, leads to abandonment.

Our audit revealed that we were asking users to think far too much. Different pieces of information occupied the same space in the UI across different states. There was no consistent visual hierarchy. Users encountering an error state in Turnstile would find information in a completely different place than they would on a Challenge Page.

We made a fundamental decision: one information architecture to rule them all.


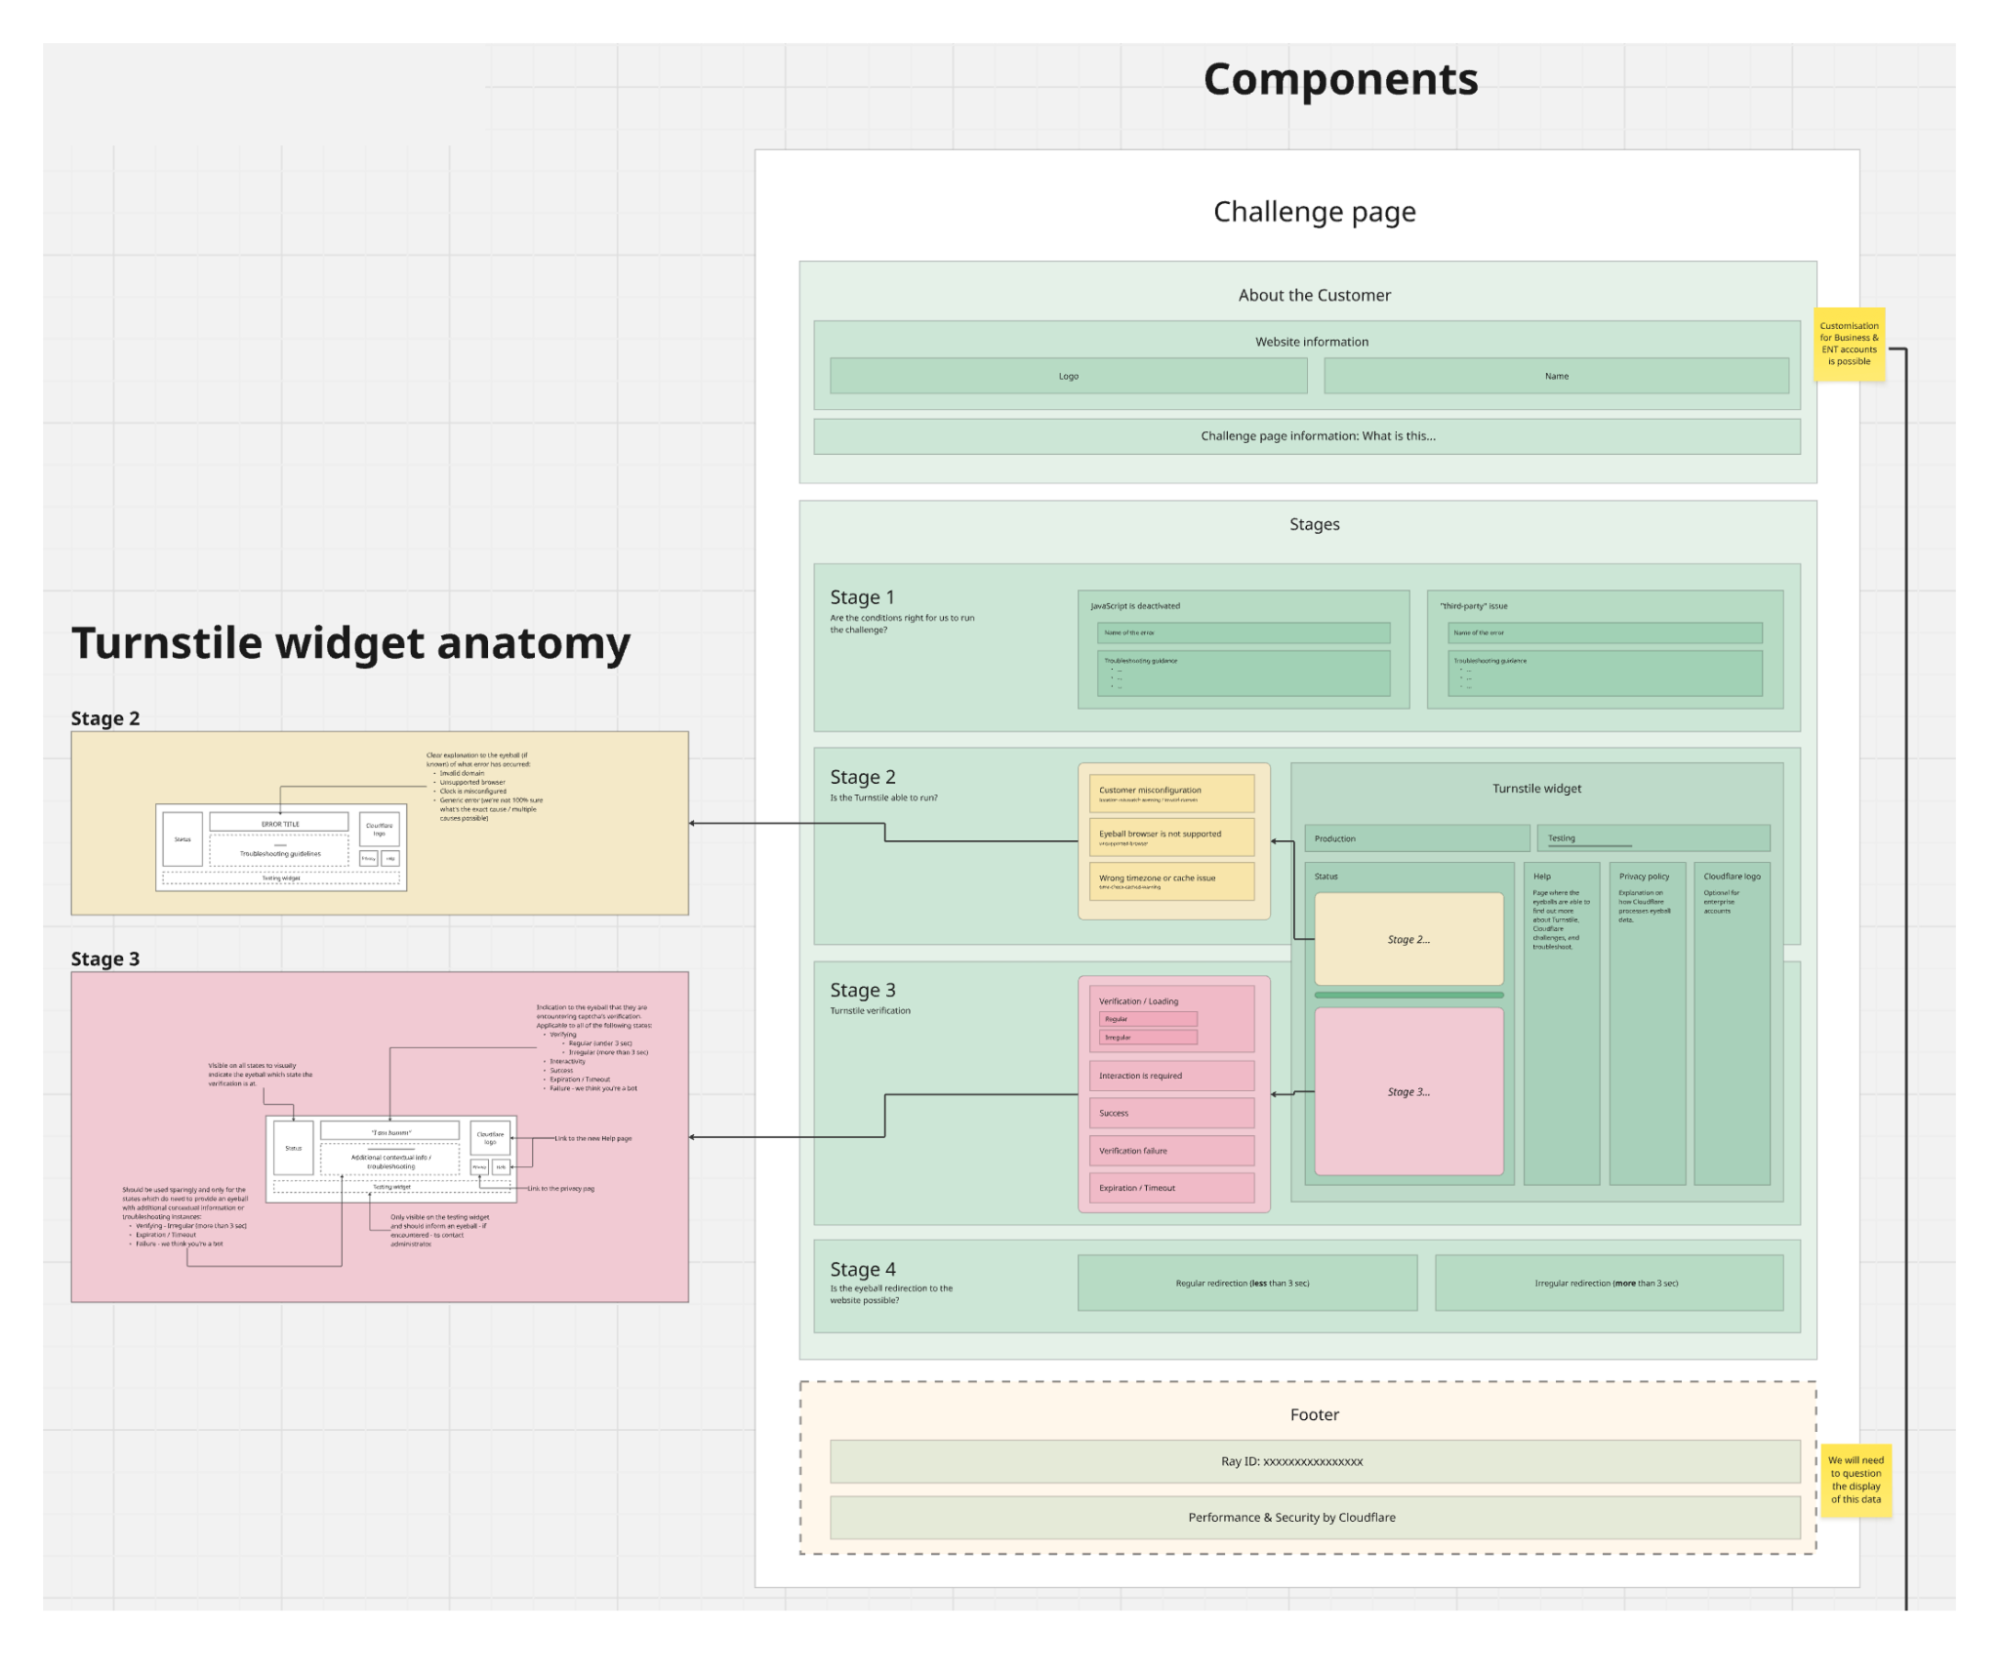
Visual diagram displaying a unified information architecture with a consistent structure across Turnstile widget and Challenge pages

Both Turnstile and Challenge Pages would now follow the same structural pattern. The same visual hierarchy. The same placement for actions, for explanatory text, for links to documentation.

Did this constrain our design options? Absolutely. We had to say no to a lot of creative ideas that didn’t fit the framework. But constraints aren’t the enemy of good design — they’re often its best friend. By limiting our options, we could go deeper on the details that actually mattered.

For users, the benefit is profound: they don’t need to re-learn what each piece of the UI means. Error states look consistent. Help links are always in the same place. Once you understand one state, you understand them all. That’s cognitive load reduced to a minimum — exactly where it should be during a security verification.

What user research taught us

How do you keep yourself accountable when redesigning something that billions of people see? You test. A lot.

We recruited 8 participants across 8 different countries, deliberately seeking diversity in age, digital savviness, and cultural background. We weren’t looking for tech-savvy early adopters — we wanted to understand how the redesign would work for everyone.

Our approach was rigorous: participants saw both the current experience and proposed changes, without knowing which was “old” or “new.” We counterbalanced positioning to eliminate bias. And we did not just test our new ideas, but also challenged our assumptions about what needed changing in the first place.


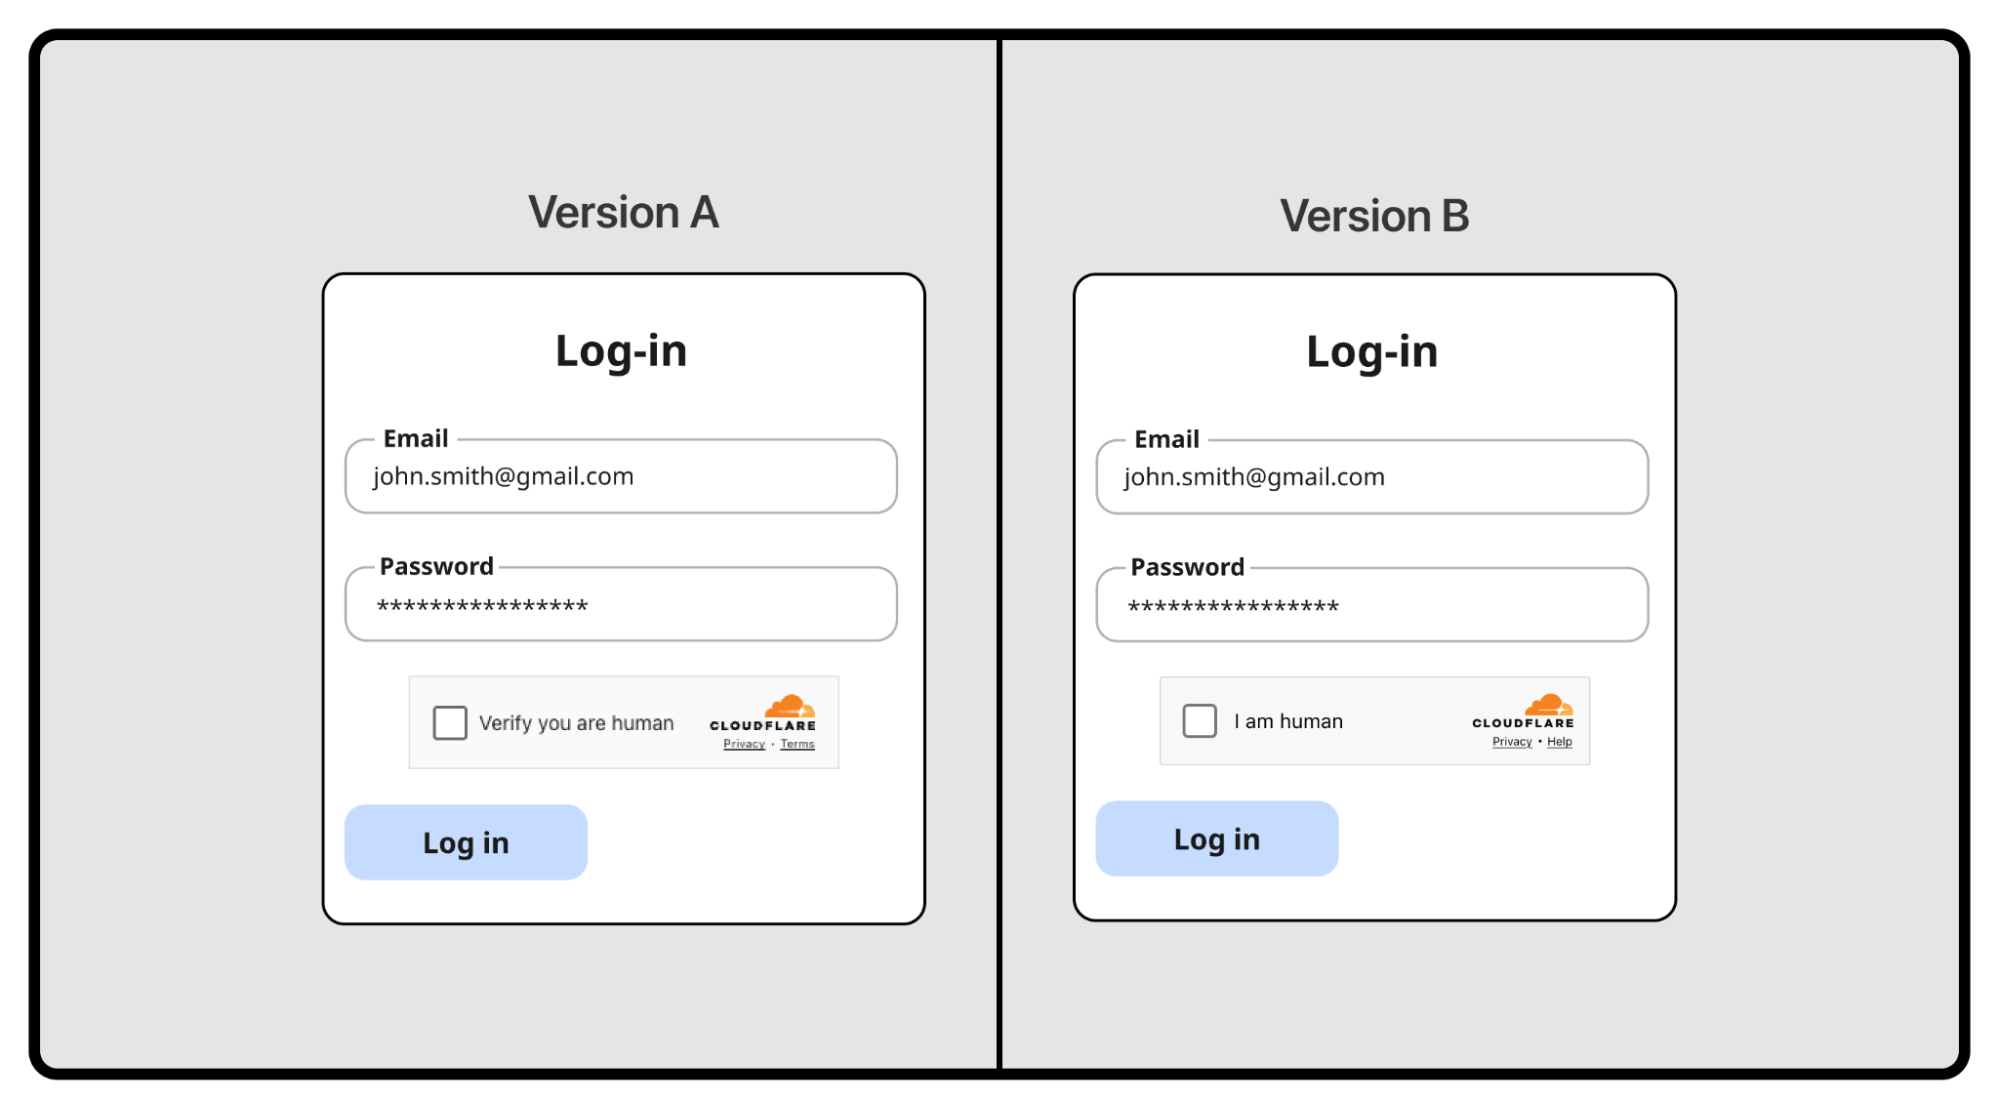
Two different versions of a Turnstile being tested in an A/B test

Some things didn’t need fixing

One hypothesis: should we align with competitors? Most CAPTCHA providers show “I am human” across all states. We use distinct content — “Verify you are human,” then “Verifying…,” then “Success!”

Were we overcomplicating things? We tested it head-to-head.

Our approach won decisively. For the interactivity state, “Verify you are human” scored 5 out of 8 points versus just 3 for “I am human.” For the verifying state, it was even more dramatic — 7.5 versus 0.5. Users wanted to know what was happening, not just be told what they were.


User testing results: users strongly favored our approach over the competitor-style design

This experiment didn’t ship as a feature, but it was invaluable. It gave us confidence we weren’t just being different for the sake of it. Some things were already right.

But these needed to change

The research surfaced four areas where we were failing users:

Help, not bureaucracy. When users encountered errors, we offered “Send Feedback.” In testing, they were baffled. “Who am I sending this to? The website? Cloudflare? My ISP?” More importantly, we discovered something fundamental: at the moment of maximum frustration, people don’t want to file a report — they want to fix the problem. We replaced “Send Feedback” with “Troubleshoot” — a single word that promises action rather than bureaucracy.


The problematic “Send Feedback” prompt: users didn’t know who they were sending feedback to

Attention, not alarm. We’d used red backgrounds liberally for errors. The reaction in testing was visceral — participants felt they had failed, felt powerless. Even for simple issues that would resolve with a retry, users assumed the worst and gave up. Red at full saturation wasn’t communicating “Here’s something to address.” It was communicating “You have failed, and there’s nothing you can do.” The fix: red only for icons, never for text or backgrounds.


The evolution: from the states with unclear error state description in red to much clearer and concise error communication in neutral-color text.

Scannable, not verbose. We’d tried to be thorough, explaining errors in technical detail. It backfired. Non-technical users found it alienating. Technical users didn’t need it. Everyone was trying to read it in the tiny real estate of a widget. The lesson: less is more, especially in constrained spaces during stressful moments.

Accessible to everyone. Our audit revealed 10px fonts in some states. Grey text that technically met AA (at least 4.5:1 for normal text and 3:1 for large text) compliance but was difficult to read in practice. “Technically compliant” isn’t good enough when you’re serving the entire Internet.

We set a clear goal: to meet the WCAG 2.2 AAA standard— the highest and most stringent level of web accessibility compliance, designed to make content accessible to the broadest range of users, including those with severe disabilities. Throughout the redesign, when visual consistency conflicted with readability, readability won. Every time.

This extended beyond vision. We designed for screen reader users, keyboard-only navigators, and people with color vision variations — going beyond what automated compliance tools can catch.

And accessibility isn’t just about impairments — it’s about language. What fits in English, overflows in German. What’s concise in Spanish is ambiguous in Japanese. Supporting over 40 languages forced us to radically simplify. The same “Unable to connect to website / Troubleshoot” pattern now works across English, Bulgarian, Danish, German, Greek, Japanese, Indonesian, Russian, Slovak, Slovenian, Serbian, Filipino, and many more.


The redesigned error state across 12 languages — consistent layout despite varying text lengths 

Final redesign

So what did we actually ship?

First, let’s talk about what we didn’t change. The happy path — “Verify you are human” → “Verifying…” → “Success!” — tested exceptionally well. Users understood what was happening at each stage. The distinct content for each state, which we’d worried might be overcomplicating things, was actually our competitive advantage.


The happy path: Verify you are human → Verifying → Success! These states tested well and remained largely unchanged

But for the states that needed work, we made significant changes guided by everything we learned.

Simplified, scannable content

We radically reduced the amount of text in error states. Instead of verbose explanations like “Your device clock is set to a wrong time or this challenge page was accidentally cached by an intermediary and is no longer available,” we now show:

  1. A clear, simple state name (e.g., “Incorrect device time”)

  2. A prominent “Troubleshoot” link

That’s it. The detailed guidance now lives in a dedicated modal screen that opens when users need it — giving them room to actually read and follow troubleshooting steps.


The troubleshooting modal: detailed guidance when users need it, without cluttering the widget

The troubleshooting modal provides context (“This error occurs when your device’s clock or calendar is inaccurate. To complete this website’s security verification process, your device must be set to the correct date and time in your time zone.”), numbered steps to try, links to documentation, and — only after the user has tried to resolve the issue — an option to submit feedback to Cloudflare. Help first, feedback second.

AAA accessibility compliance

Every state now meets WCAG 2.2 AAA standards for contrast and readability. Font sizes have established minimums. Interactive elements are clearly focusable and properly announced by screen readers.

Unified experience across Turnstile and Challenge pages

Whether users encounter the compact Turnstile widget or a full Challenge Page, the information architecture is now consistent. Same hierarchy. Same placement. Same mental model.

Challenge Pages now follow a clean structure: the website name and favicon at the top, a clear status message (like “Verification successful” or “Your browser is out of date”), and actionable guidance below. No more walls of orange or red text. No more technical jargon without context.


Re-designed Challenge page states with clear troubleshooting instructions.

Validated across languages

Every piece of content was tested in over 40 supported languages. Our process involved three layers of validation:

  1. Initial design review by the design team

  2. Professional translation by our qualified vendor

  3. Final review by native-speaking Cloudflare employees

This wasn’t just about translation accuracy — it was about ensuring the visual design held up when content length varied dramatically between languages.

The complete picture

The result is a security verification experience that’s clearer, more accessible, less frustrating, and — crucially — just as secure. We didn’t compromise on protection to improve the experience. We proved that good design and strong security aren’t in conflict.


Re-designed Turnstile widgets on the left and a re-designed Challenge page on the right

But designing the experience was only half the battle. Shipping it to billions of users? That’s where Ana comes in.

Part 2: Shipping to billions

Beyond centering a div

Some may say the hardest part of being a Frontend Engineer is centering a div. In reality, the real challenge often lies much deeper, especially when working close to the platform primitives. Building a critical piece of Internet infrastructure using native APIs forces you to think differently about UI development, tradeoffs, and long-term maintainability.

In our case, we use Rust to handle the UI for both the Turnstile widget and the Challenge page. This decision brought clear benefits in terms of safety and consistency across platforms, but it also increased frontend complexity. Many of us are used to the ergonomics of modern frameworks like React, where common UI interactions come almost for free. Working with Rust meant reimplementing even simple interactions using lower level constructs like document.getElementById, createElement, and appendChild.

On top of that, compile times and strict checks naturally slowed down rapid UI iteration compared to JavaScript based frameworks. Debugging was also more involved, as the tooling ecosystem is still evolving. These constraints pushed us to be more deliberate, more thoughtful, and ultimately more disciplined in how we approached UI development.

Small visual changes, big global impact

What initially looked like small visual tweaks such as padding adjustments or alignment changes quickly revealed a much bigger challenge: internationalization.

Once translations were available, we had to ensure that content remained readable and usable across 38 languages and 16 different UI states. Text length variability alone required careful design decisions. Some translations can be 30 to 300 percent longer than English. A short English string like “Stuck?” becomes “Tidak bisa melanjutkan?” in Indonesian or “Es geht nicht weiter?” in German, dramatically changing layout requirements.

Right-to-left language support added another layer of complexity. Supporting Arabic, Persian or Farsi, and Hebrew meant more than flipping text direction. Entire layouts had to be mirrored, including alignment, navigation patterns, directional icons, and animation flows. Many of these elements are implicitly designed with left-to-right assumptions, so we had to revisit those decisions and make them truly bidirectional.

Ordered lists also required special care. Not every culture uses the Western 1, 2, 3 numbering system, and hardcoding numeric sequences can make interfaces feel foreign or incorrect. We leaned on locale-aware numbering and fully translatable list formats to ensure ordering felt natural and culturally appropriate in every language.

Building confidence through testing

As we started listing action points in feedback reports, correctness became even more critical. Every action needed to render properly, trigger the right flow, and behave consistently across states, languages, and edge cases.

To get there, we invested heavily in testing. Unit tests helped us validate logic in isolation, while end-to-end tests ensured that new states and languages worked as expected in real scenarios. This testing foundation gave us confidence to iterate safely, prevented regressions, and ensured that feedback reports remained reliable and actionable for users.

The outcome

What began as a set of technical constraints turned into an opportunity to build a more robust, inclusive, and well-tested UI system. Working with fewer abstractions and closer to the browser primitives forced us to rethink assumptions, improve our internationalization strategy, and raise the overall quality bar.

The result is not just a solution that works, but one we trust. And that trust is what allows us to keep improving, even when centering a div turns out to be the easy part.

Part 3: The impact

Designing for billions of people is a responsibility we take seriously. At this scale, it is essential to leverage measurable data to tell us the real impact of our design choices. As we prepare to roll out these changes, we are focusing on five key metrics that will tell us if we’ve truly succeeded in making the Internet’s most-seen UI more human.

1. Challenge Completion Rate

Our primary north star is the Challenge Solve Rate: the percentage of issued challenges that are successfully completed. By moving away from technical jargon like “intermediary caching” and toward simple, actionable labels like “Incorrect device time,” we expect a significant uptick in CSR. A higher CSR doesn’t mean we’re being easier on bots; it means we’re removing the hurdles that were accidentally tripping up legitimate human users.

2. Time to Complete

Every second a user spends on a challenge page is a second they aren’t getting the information that they need. Our research showed that users were often paralyzed by choice when seeing a wall of red text. With our new scannable, neutral-color design, we are tracking Time to Complete to ensure users can identify and resolve issues in seconds rather than minutes.

3. Abandonment Rate Changes

In the past, our liberal use of “saturated red” caused a visceral reaction: users felt they had failed and simply gave up. By reserving red only for icons and using a unified architecture, we aim to reduce Abandonment Rates. We want users to feel empowered to click Troubleshoot rather than feeling powerless and clicking away.

4. Support Ticket Volume

One of the bigger shifts from a product perspective is our new Troubleshooting Modal. By providing clear, numbered steps directly within the widget, we are building self-service support into the UI. We expect this to result in a measurable decrease in support ticket volume for both our customers and our own internal teams.

5. Social Sentiment

We know that security challenges are rarely loved, but they shouldn’t be hated because they are confusing. We are monitoring Social Sentiment across community forums, feedback reports, and social channels to see if the conversation shifts from “this widget is broken” to “I had an issue, but I fixed it”.

As a Product Manager, my goal is often invisible security — the best challenge is the one the user never sees. But when a challenge must be seen, it should be an assistant, not a bouncer. This redesign proves that AAA accessibility and high-security standards aren’t in competition; they are two sides of the same coin. By unifying the architecture of Turnstile and Challenge Pages, we’ve built a foundation that allows us to iterate faster and protect the Internet more humanely than ever before.

Looking ahead

This redesign is a foundation, not a finish line.

We’re continuing to monitor how users interact with the new experience, and we’re committed to iterating based on what we learn. The feedback mechanisms we’ve built into the new design — the ones that actually help users troubleshoot, rather than just asking them to report problems — will give us richer insights than we’ve ever had before.

We’re also watching how the security landscape evolves. As bot attacks grow more sophisticated, and as AI continues to blur the line between human and automated behavior, the challenge of verification will only get harder. Our job is to stay ahead — to keep improving security without making the human experience worse.

If you encounter the new Turnstile or Challenge Pages and have feedback, we want to hear it. Reach out through our community forums or use the feedback mechanisms built into the experience itself.

Design system annotations, part 2: Advanced methods of annotating components

Post Syndicated from Jan Maarten original https://github.blog/engineering/user-experience/design-system-annotations-part-2-advanced-methods-of-annotating-components/


In part one of our design system annotation series, we discussed the ways in which accessibility can get left out of design system components from one instance to another. Our solution? Using a set of “Preset annotations” for each component with Primer. This allows designers to include specific pre-set details that aren’t already built into the component and visually communicated in the design itself. 

That being said, Preset annotations are unique to each design system — and while ours may be a helpful reference for how to build them — they’re not something other organizations can utilize if you’re not also using the Primer design system. 

Luckily, you can build your own. Here’s how. 

How to make Preset annotations for your design system

Start by assessing components to understand which ones would need Preset annotations—not all of them will. Prioritize components that would benefit most from having a Preset annotation, and build that key information into each one. Next, determine what properties should be included. Only include key information that isn’t conveyed visually, isn’t in the component properties, and isn’t already baked into a coded component. 

The start of a list of Primer components with notes for those which need Preset annotations. There are notes pointing to ActionBar, ActionMenu, and Autocomplete with details about what information should be documented in their Preset.

Prioritizing components

When a design system has 60+ components, knowing where to start can be a challenge. Which components need these annotations the most? Which ones would have the highest impact for both design teams and our users? 

When we set out to create a new set of Preset annotations based on our proof of concept, we decided to use ten Primer components that would benefit the most. To help pick them, we used an internal tool called Primer Query that tracks all component implementations across the GitHub codebase as well as any audit issues connected to them. Here is a video breakdown of how it works, if you’re curious. 

We then prioritized new Preset annotations based on the following criteria:

  1. Components that align to organization priorities (i.e. high value products and/or those that receive a lot of traffic).
  2. Components that appear frequently in accessibility audit issues.
  3. Components with React implementations (as our preferred development framework).
  4. Most frequently implemented components. 

Mapping out the properties

For each component, we cross-referenced multiple sources to figure out what component properties and attributes would need to be added in each Preset annotation. The things we were looking for may only exist in one or two of those places, and thus are less likely to be accounted for all the way through the design and development lifecycle. The sources include:

Component documentation on Primer.style

Design system docs should contain usage guidance for designers and developers, and accessibility requirements should be a part of this guidance as well. Some of the guidance and requirements get built into the component’s Figma asset, while some only end up in the coded component. 

Look for any accessibility requirements that are not built into either Figma or code. If it’s built in, putting the same info in the Preset annotation may be redundant or irrelevant.

Coded demos in Storybook 

Our component sandbox helped us see how each component is built in React or Rails, as well as what the HTML output is. We looked for any code structure or accessibility attributes that are not included in the component documentation or the Figma asset itself—especially when they may vary from one implementation to another. 

Component properties in the Figma asset library

Library assets provide a lot of flexibility through text layers, image fills, variants, and elaborate sets of component properties. We paid close attention to these options to understand what designers can and can’t change. Worthwhile additions to a Preset Annotation are accessibility attributes, requirements, and usage guidance in other sources that aren’t built into the Figma component. 

Other potential sources 

  • Experiences from team members: The designers, developers, and accessibility specialists you work with may have insight into things that the docs and design tools may have missed. If your team and design system have been around for a while, their insights may be more valuable than those you’ll find in the docs, component demos, or asset libraries. Take some time to ask which components have had challenging bugs and which get intentionally broken when implemented.
  • Findings from recent audits: Design system components themselves may have unresolved audit issues and remediation recommendations. If that’s the case, those issues are likely present in Storybook demos and may be unaccounted for in the component documentation. Design system audit issues may have details that both help create a Preset annotation and offer insights about what should not be carried over from existing resources.

What we learned from creating Preset annotations

Preset annotations may not be for every team or organization. However, they are especially well suited for younger design systems and those that aren’t well adopted. 

Mature design systems like Primer have frequent updates. This means that without close monitoring, the design system components themselves may fall out of sync with how a Preset annotation is built. This can end up causing confusion and rework after development starts, so it may be wise to make sure there’s some capacity to maintain these annotations after they’ve been created. 

For newer teams at GitHub, new members of existing teams, and team members who were less familiar with the design system, the built-in guidance and links to documentation and component demos proved very useful. Those who are more experienced are also able to fine-tune the Presets and how they’re used.

If you don’t already have extensive experience with the design system components (or peers to help build them), it can take a lot of time to assess and map out the properties needed to build a Preset. It can also be challenging to name a component property succinctly enough that it doesn’t get truncated in Figma’s properties panel. If the context is not self-evident, some training or additional documentation may help.

It’s not always clear that you need a Preset annotation

There may be enough overlap between the Preset annotation for a component and types of annotations that aren’t specific to the design system. 
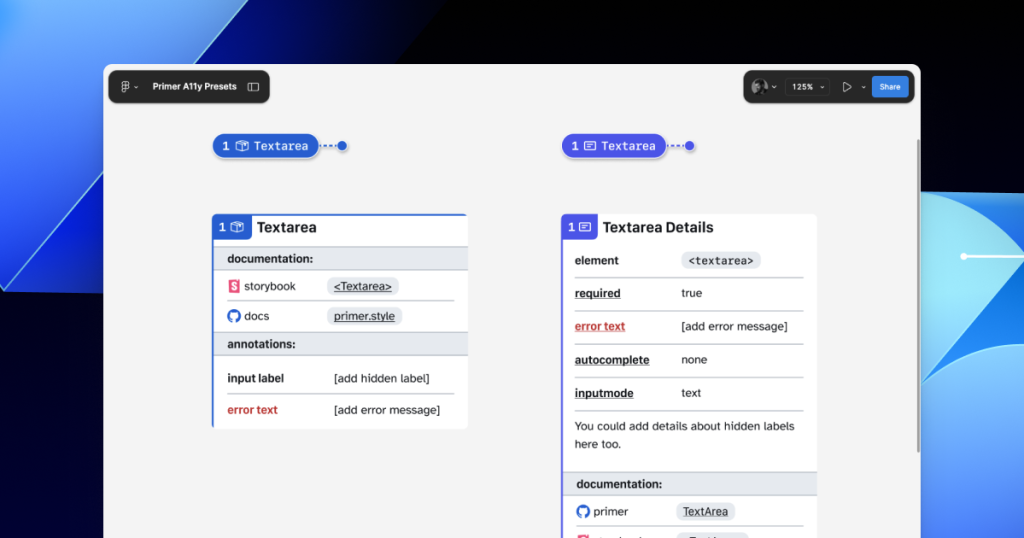
For example, the GitHub Annotation Toolkit has components to annotate basic <textarea> form elements in addition to a Preset annotation for our <TextArea> Primer component:

Comparison between a Form Element annotation for the textarea HTML element and a Preset annotation for the TextArea Primer component.

In many instances, this flexibility may be confusing because you could use either annotation. For example, the Primer <TextArea> Preset has built-in links to specific Primer docs, and while the non-Preset version doesn’t, you could always add the links manually. While there’s some overlap between the two, using either one is better than none. 

One way around this confusion is to add Primer-specific properties to the default set of annotations. This would allow you to do things like toggle a boolean property on a normal Button annotation and have it show links and properties specific to your design system’s button component. 

Our Preset creation process may unlock automation

There are currently a number of existing Figma plugins that advertise the ability to scan a design file to help with annotations. That being said, the results are often mixed and contain an unmanageable amount of noise and false positives. One of the reasons these issues happen is that these public plugins are design system agnostic.

Current automated annotation tools aren’t able to understand that any design system components are being used without bespoke programming or thorough training of AI models. For plugins like this to be able to label design elements accurately, they first need to understand how to identify the components on the canvas, the variants used, and the set properties. 

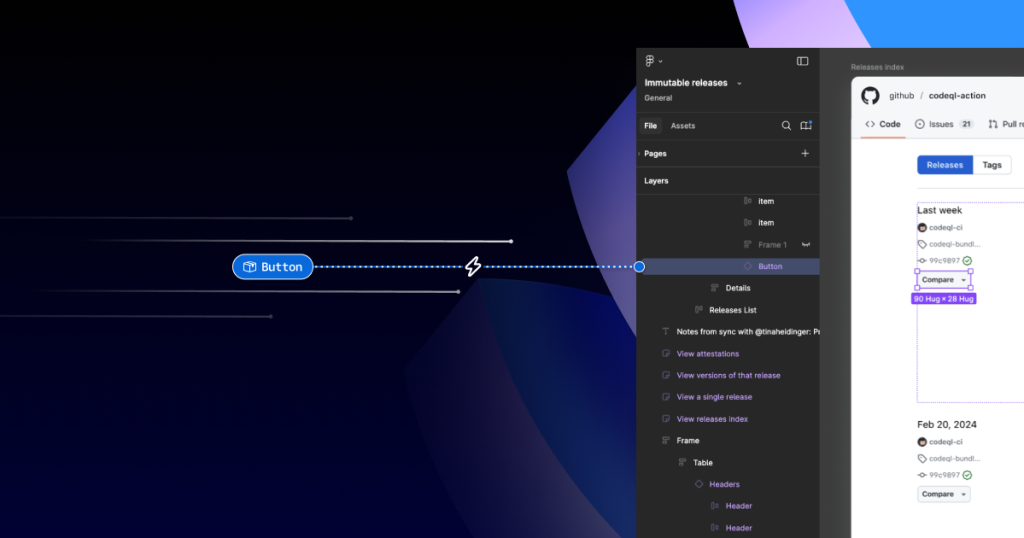
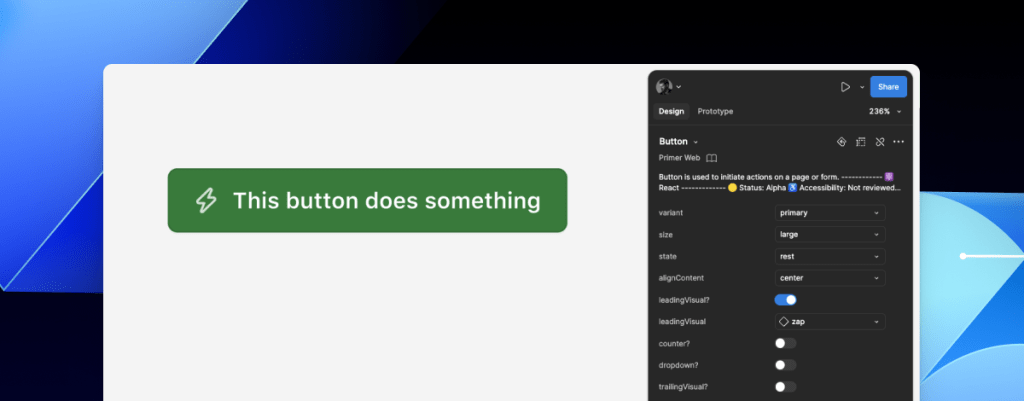
A Figma file showing an open design for Releases with an expanded layer tree highlighting a Primer Button component in the design. To the left of the screenshot are several git-lines and a Preset annotation for a Primer Button with a zap icon intersecting it. The git-line trails and the direction of the annotation give the feeling of flying toward the layer tree, which visually suggests this Primer Button layer can be automatically identified and annotated.

With that in mind, perhaps the most exciting insight is that the process of mapping out component properties for a Preset annotation—the things that don’t get conveyed in the visual design or in the code—is also something that would need to be done in any attempt to automate more usable annotations. 

In other words, if a team uses a design system and wants to automate adding annotations, the tool they use would need to understand their components. In order for it to understand their components well enough to automate accurately, these hidden component properties would need to be mapped out. The task of creating a set of Preset annotations may be a vital stepping stone to something even more streamlined. 

A promising new method: Figma’s Code Connect 

While building our new set of Preset annotations, we experimented with other ways to enhance Primer with annotations. Though not all of those experiments worked out, one of them did: adding accessibility attributes through Code Connect. 

Primer was one of the early adopters of Figma’s new Code Connect feature in Dev Mode. Says Lukas Oppermann, our staff systems designer, “With Code Connect, we can actually move the design and the code a little bit further apart again. We can concentrate on creating the best UX for the designers working in Figma with design libraries and, on the code side, we can have the best developer experience.” 

To that end, Code Connect allows us to bypass much of our Preset annotations, as well as the downsides of some of our other experiments. It does this by adding key accessibility details directly into the code that developers can export from Figma.

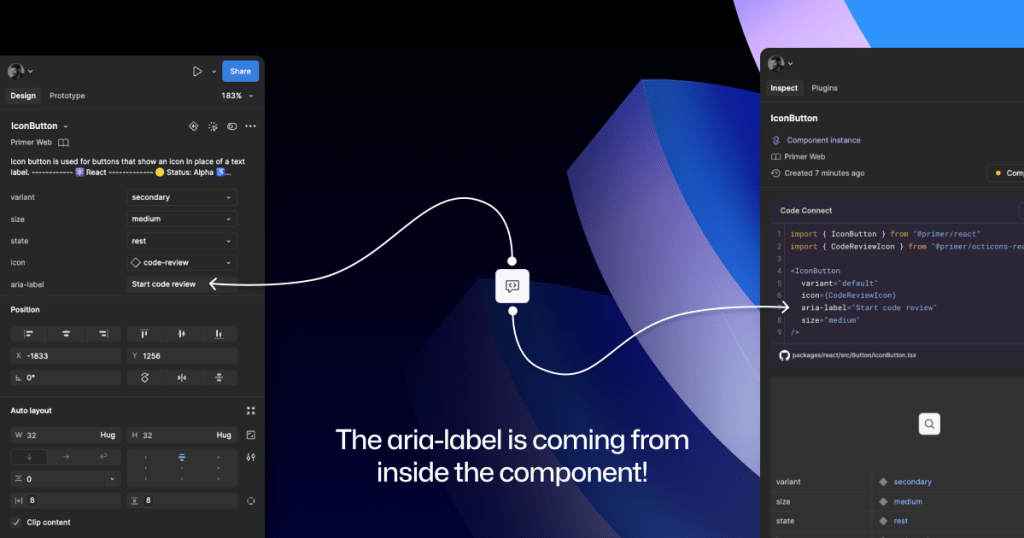
GitHub’s Octicons are used in many of our Primer components. They are decorative by default, but they sometimes need alt text or aria-label attributes depending on how they’re used. In the IconButton component, that button uses an Octicon and needs an accessible name to describe its function. 

When using a basic annotation kit, this may mean adding stamps for a Button and Decorative Image as well as a note in the margins that specifies what the aria-label should be. When using Preset annotations, there are fewer things to add to the canvas and the annotation process takes less time.

With Code Connect set up, Lukas added a hidden layer in the IconButton Figma component. It has a text property for aria-label which lets designers add the value directly from the component properties panel. No annotations needed. The hidden layer doesn’t disrupt any of the visuals, and the aria-label property gets exported directly with the rest of the component’s code.

An IconButton component with a code-review icon. On the left is a screenshot of the component’s properties panel, with an aria-label value of: Start code review. On the right is the Code Connect output showing usable React code for an IconButton that includes the parameter: aria-label=Start code review.

It takes time to set up Code Connect with each of your design system components. Here are a few tips to help:

  • Consistency is key. Make sure that the properties you create and how you place hidden layers is consistent across components. This helps set clear expectations so your teams can understand how these hidden layers and properties function. 
  • Use a branch of your design system library to experiment. Hiding attributes like aria-label is quite simple compared to other complex information that Preset annotations are capable of handling. 
  • Use visual regression testing (VRT). Adding complexity directly to a component comes with increased risk of things breaking in the future, especially for those with many variants. Figma’s merge conflict UI is helpful, but may not catch everything.

We’ve made the GitHub Annotation Toolkit open source, so you can see first-hand how we’ve implemented our Primer A11y Preset annotations and visual regression tests. Check it out and start annotating today!

Figma library cover for the GitHub Annotation Toolkit with a grid background that looks like a starry night sky. There's an armada of little annotation stamp labels covering the bottom two thirds of the image, all at an angle. There's a series of angled git lines above them. Both look like they're launching from the ground and through into the sky grid.

Further reading

Accessibility annotation kits are a great resource, provided they’re used responsibly. Eric Bailey, one of the contributors to our forthcoming GitHub Annotation Toolkit, has written extensively about how annotations can highlight and amplify deeply structural issues when you’re building digital products.

The post Design system annotations, part 2: Advanced methods of annotating components appeared first on The GitHub Blog.
Design system annotations, part 1: How accessibility gets left out of components

Post Syndicated from Jan Maarten original https://github.blog/engineering/user-experience/design-system-annotations-part-1-how-accessibility-gets-left-out-of-components/


When it comes to design systems, every organization tends to be at a different place in their accessibility journey. Some have put a great deal of work into making their design system accessible while others have a long way to go before getting there. To help on this journey, many organizations rely on accessibility annotations to make sure there are no access barriers when a design is ready to be built. 

However, it’s a common misconception (especially for organizations with mature design systems) that accessible components will result in accessible designs. While design systems are fantastic for scaling standards and consistency, they can’t prevent every issue with our designs or how we build them. Access barriers can still slip through the cracks and make it into production.

This is the root of the problem our Accessibility Design team set out to solve. 

In this two-part series, we’ll show you exactly how accessible design system components can produce inaccessible designs. Then we’ll demonstrate our solution: integrating annotations with our Primer components. This allows us to spend less time annotating, increases design system adoption, and reaches teams who may not have accessibility support. And in our next post, we’ll walk you through how you can do the same for your own components.

Let’s dig in.

What are annotations and their benefits? 

Annotations are notes included in design projects that help make the unseen explicit by conveying design intent that isn’t shown visually. They improve the usability of digital experiences by providing a holistic picture for developers of how an experience should function. Integrating annotations into our design process helps our teams work better together by closing communication gaps and preventing quality issues, accessibility audit issues, and expensive re-work. 

Some of the questions annotations help us answer include:

  • How is assistive technology meant to navigate a page from one element to another?
  • What’s the alternative text for informative images and buttons without labels?
  • How does content shift depending on viewport size, screen orientation, or zoom level?
  • Which virtual keyboard should be used for a form input on mobile?
  • How should focus be managed for complex interactions?

Our answers to questions like this—or the lack thereof—can make or break the experience of the web for a lot of people, especially users with disabilities. Some annotation tools are built specifically to help with this by guiding designers to include key details about web standards, platform functionality, and accessibility (a11y). 

Most public annotation kits are well suited for teams who are creating new design system components, teams who aren’t already using a design system, or teams who don’t have specialized accessibility knowledge. They usually help annotate things like:

  • Controls such as buttons and links
  • Structural elements such as headings and landmarks
  • Decorative images and informative descriptions 
  • Forms and other elements that require labels and semantic roles 
  • Focus order for assistive technology and keyboard navigation

GitHub’s annotation’s toolkit

One of our top priorities is to meet our colleagues where they’re at. We wanted all our designers to be able to use annotations out of the box because we believe they shouldn’t need to be a certified accessibility specialist in order to get things built in an accessible way. 

 A browser window showing the Web Accessibility Annotation Kit in the cvs-health/annotations repository.

To this end, last year we began creating an internal Figma library—the GitHub Annotation Toolkit—which is now open source! Our toolkit builds on the legacy of the former Inclusive Design team at CVS Health. Their two open source annotation kits help make documentation that’s easy to create and consume, and are among the most widely used annotation libraries in the Figma Community. 

While they add clarity, annotations can also add overhead. If teams are only relying on specialists to interpret designs and technical specifications for developers, the hand-off process can take longer than it needs to. To create our annotation toolkit, we rebuilt its predecessor from the ground up to avoid that overhead, making extensive improvements and adding inline documentation to make it more intuitive and helpful for all of our designers—not just accessibility specialists. 

Design systems can also help reduce that overhead. When you audit your design systems for accessibility, there’s less need for specialist attention on every product feature, since you’re using annotations to add technical semantics and specialist knowledge into every component. This means that designers and developers only need to adhere to the usage guidelines consistently, right?

The problems with annotations and design system components

Unfortunately, it’s not that simple. 

Accessibility is not binary

While design systems can help drive more accessible design at scale, they are constantly evolving and the work on them is never done. The accessibility of any component isn’t binary. Some may have a few severe issues that create access barriers, such as being inoperable with a keyboard or missing alt text. Others may have a few trivial issues, such as generic control labels. 

Most of the time, it will be a misnomer to claim that your design system is “fully accessible.” There’s always more work to do—it’s just a question of how much. The Web Content Accessibility Guidelines (WCAG) are a great starting point, but their “Success Criteria” isn’t tailored for the unique context that is your website or product or audience. 

While the WCAG should be used as a foundation to build from, it’s important to understand that it can’t capture every nuance of disabled users’ needs because your users’ needs are not every user’s needs. It would be very easy to believe that your design system is “fully accessible” if you never look past WCAG to talk to your users. If Primer has accessible components, it’s because we feel that direct participation and input from daily assistive technology users is the most important aspect of our work. Testing plans with real users—with and without disabilities—is where you really find what matters most. 

Accessible components do not guarantee accessible designs

Arranging a series of accessible components on a page does not automatically create an accurate and informative heading hierarchy. There’s a good chance that without additional documentation, the heading structure won’t make sense visually—nor as a medium for navigating with assistive technology.

A page wireframe showing a linear layout of an H1 title, an H2 in a banner below it, and a row of several cards below with headings of H4. The caption reads: this accessible card has an H4, breaking the page structure by skipping heading levels. Next to the wireframe is a diagram showing the page structure as a tree view, highlighting the level skipping from H2 to H4.

It’s great when accessible components are flexible and responsive, but what about when they’re placed in a layout that the component guidance doesn’t account for? Do they adapt to different zoom levels, viewport sizes, and screen orientations? Do they lose any functionality or context when any of those things change?

Component usage is contextual. You can add an image or icon to your design, but the design system docs can’t write descriptive text for you. You can use the same image in multiple places, but the image description may need to change depending on context. 

Similarly, forms built using the same input components may do different things and require different error validation messages. It’s no wonder that adopting design system components doesn’t get rid of all audit issues.

Design system components in Figma don’t include all the details

Annotation kits don’t include components for specific design systems because almost every organization is using their own. When annotation kits are adopted, teams often add ways to label their design system components. 

This labeling lets developers know they can use something that’s already been built, and that they don’t need to build something from scratch. It also helps identify any design system components that get ‘detached’ in Figma. And it reduces the number of things that need to be annotated. 

Let’s look at an example:

A green Primer button with a lightning bolt icon and a label that says: this button does something. To the right is a set of Figma component properties that control the button’s visual appearance.

If we’re using this Primer Button component from the Primer Web Figma library, there are a few important things that we won’t know just by looking at the design or the component properties:

  • Functional differences when components are implemented. Is this a link that just looks visually like a button? If so, a developer would use the <LinkButton> React component instead of <Button>.
  • Accessible labels for folks using assistive technology. The icon may need alt text. In some cases, the button text might need some visually-hidden text to differentiate it from similar buttons. How would we know what that text is? Without annotations, the Figma component doesn’t have a place to display this.
  • Whether user data is submitted. When a design doesn’t include an obvious form with input fields, how do we convey that the button needs specific attributes to submit data? 

It’s risky to leave questions like this unanswered, hoping someone notices and guesses the correct answer. 

A solution that streamlines the annotation process while minimizing risk

When creating new components, a set of detailed annotations can be a huge factor in how robust and accessible they are. Once the component is built, design teams can start to add instances of that component in their designs. When those designs are ready to be annotated, those new components shouldn’t need to be annotated again. In most cases, it would be redundant and unnecessary—but not in every case. 

There are some important details in many Primer components that may change from one instance to another. If we use the CVS Health annotation kit out of the box, we should be able to capture those variations, but we wouldn’t be able to avoid those redundant and unnecessary annotations. As we built our own annotation toolkit, we built a set of annotations for each Primer component to do both of those things at once. 

An annotated Primer Brand accordion with six Stamps and four Detail notes in the margins.

This accordion component has been thoroughly annotated so that an engineer has everything they need to build it the first time. These include heading levels, semantics for <detail> and <summary> elements, landmarks, and decorative icons. All of this is built into the component so we don’t need to annotate most of this when adding the accordion to our new designs.

However, there are two important things we need to annotate, as they can change from one instance to another:

  1. The optional title at the top.
  2. The heading level of each item within the accordion.

If we don’t specify these things, we’re leaving it to chance that the page’s heading structure will break or that the experience will be confusing for people to understand and navigate the page. The risks may be low for a single button or basic accordion, but they grow with pattern complexity, component nesting, interaction states, duplicated instances, and so on. 

An annotated Primer Brand accordion with one Stamp and one Detail note in the margins.

Instead of annotating what’s already built into the component or leaving these details to chance, we can add two quick annotations. One Stamp to point to the component, and one Details annotation where we fill in some blanks to make the heading levels clear. 

Because the prompts for specific component details are pre-set in the annotation, we call them Preset annotations.

A mosaic of preset annotation for various Primer components.

Introducing our Primer A11y Preset annotations

With this proof of concept, we selected ten frequently used Primer components for the same treatment and built a new set of Preset annotations to document these easily missed accessibility details—our Primer A11y Presets. 

Those Primer components tend to contribute to more accessibility audit issues when key details are missing on implementation. Issues for these components relate to things like lack of proper labels, error validation messages, or missing HTML or ARIA attributes

IconButton Preset annotation, with guidance toggled on.

Each of our Preset annotations is linked to component docs and Storybook demos. This will hopefully help developers get straight to the technical info they need without designers having to find and add links manually. We also included guidance for how to fill out each Preset, as well as how to use the component in an accessible way. This helps designers get support inline without leaving their Figma canvas. 

Want to create your own? Check out Design system annotations, part 2

Button components in Google’s Material Design and Shopify’s Polaris, IBM’s Carbon, or our Primer design system are all very different from one another. Because Preset annotations are based on specific components, they only work if you’re also using the design system they’re made for. 

In part 2 of this series, we’ll walk you through how you can build your own set of Preset annotations for your design system, as well as some different ways to document important accessibility details before development starts.

You may also like: 

If you’re more of a visual learner, you can watch Alexis Lucio explore Preset annotations during GitHub’s Dev Community Event to kick off Figma’s Config 2024. 

Get the guide to GitHub’s Annotation Toolkit >

The post Design system annotations, part 1: How accessibility gets left out of components appeared first on The GitHub Blog.
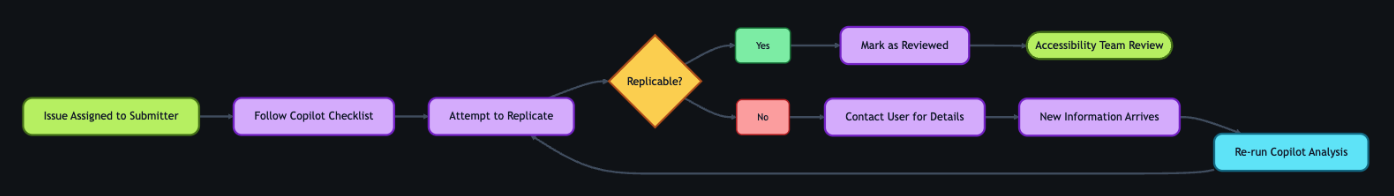
Building a more accessible GitHub CLI

Post Syndicated from Ryan Hecht original https://github.blog/engineering/user-experience/building-a-more-accessible-github-cli/


At GitHub, we’re committed to making our tools truly accessible for every developer, regardless of ability or toolset. The command line interface (CLI) is a vital part of the developer experience, and the GitHub CLI is our product that brings the power of GitHub to your terminal.

When it comes to accessibility, the terminal is fundamentally different from a web browser or a graphical user interface, with a lineage that predates the web itself. While standards like the Web Content Accessibility Guidelines (WCAG) provide a clear path for making web and graphical applications accessible, there is no equivalent, comprehensive standard for the terminal and CLIs. The W3C offers some high-level guidance for non-web software, but it stops short of prescribing concrete techniques, leaving much open to interpretation and innovation.

This gap has challenged us to think creatively and purposefully about what accessibility should look like in the terminal. Our recent Public Preview is focused on addressing the needs of three key groups: users who rely on screen readers, users who need high contrast between background and text, and users who require customizable color options. Our work aims to make the GitHub CLI more inclusive for all, regardless of how you interact with your terminal. Run gh a11y in the latest version of the GitHub CLI to enable these features, or read on to learn about our path to designing and implementing them.

Understanding the terminal landscape

Text-based and command-line applications differ fundamentally from graphical or web applications. On a web page, assistive technologies like screen readers make use of the document object model (DOM) to infer structure and context of the page. Web pages can be designed such that the DOM’s structure is friendly to these technologies without impacting the visual design of the page.  By contrast, CLI’s primary output is plain text, without hidden markup. A terminal emulator acts as the “user agent” for text apps, rendering characters as directed by the server application. Assistive technologies access this matrix of characters, analyze its layout, and try to infer structure. As the WCAG2ICT guidance notes, accessibility in this space means ensuring that all text output is available to assistive technologies, and that structural information is conveyed in a way that’s programmatically determinable—even if no explicit markup is present.

In our quest to improve the GitHub CLI’s usability for blind, low-vision, and colorblind users, we found ourselves navigating a landscape with lots of guidance, but few concrete techniques for implementing accessible experiences. We studied how assistive technology interacts with terminals: how screen readers review output, how color and contrast can be customized, and how structural cues can be inferred from plain text. Our recent Public Preview contains explorations into various use cases in these spaces. 

Rethinking prompts and progress for screen readers

One of the GitHub CLI’s strengths as a command-line application is its rich prompting experience, which gives our users an interactive interface to enter command options. However, this rich interactive experience poses a hurdle for speech synthesis screen readers: Non-alphanumeric visual cues and uses of constant screen redraws for visual or other effects can be tricky to correctly interpret as speech.


A demo video with sound of screen reader reading legacy prompter.

To reduce confusion and make it easier for blind and low vision users to confidently answer questions and navigate choices, we’re introducing a prompting experience that allows speech synthesis screen readers to accurately convey prompts to users. Our new prompter is built using Charm’s open source charmbracelet/huh prompting library.

A demo of a screenreader correctly reading a prompt.

Another use case where the terminal is redrawn for visual effect is when showing progress bars. Our existing implementation uses a “spinner” made by redrawing the screen to display different braille characters (yes, we appreciate the irony) to give the user the indication that their command is executing. Speech synthesis screen readers do not handle this well:

A demo of a screenreader and an old spinner.

This has been replaced with a static text progress indicator (with a relevant message to the action being taken where possible, falling back to a general “Working…” message). We’re working on identifying other areas we can further improve the contextual text.

A demo video of the new progress indicator experience.

Color, contrast, and customization

Color is more than decoration in the terminal: It’s a vital tool for highlighting information, signaling errors, and guiding workflows. But color can also be a barrier—if contrast between the color of the terminal background and the text displayed on it is too low, some users will have difficulty discerning the displayed information. Unlike in a web browser, a terminal’s background color is not set by the application. That task is handled by the user’s terminal emulator. In order to maintain contrast, it is important that a command line application takes into account this variable.

Our legacy color palette used for rendering Markdown did not take the terminal’s background color into account, leading to low contrast in some cases.

A screenshot of the legacy Markdown palette.

The colors themselves also matter. Different terminal environments have varied color capabilities (some support 4-bit, some 8-bit, some 24-bit, etc). No matter the capability, terminals enable users to customize their color preferences, choosing how different hues are displayed. However, most terminals only support changing a limited subset of colors: namely, the sixteen colors in the ANSI 4-bit color table. The GitHub CLI has made extensive efforts to align our color palettes to 4-bit colors so our users can completely customize their experience using their terminal preferences. We built on top of the accessibility foundations pioneered by Primer when deciding which 4-bit colors to use.

A screenshot showing the improved Markdown palette.

Building for the CLI community

Our improvements aim to support a wide range of developer needs, from blind users who need screen readers, to low vision users who need high contrast, to colorblind users who require customizable color options. But this Public Preview does not mark the end of our team’s commitment to enabling all developers to use the GitHub CLI. We intend to make it easier for our extension authors to implement the same accessibility improvements that we’ve made to the core CLI. This will allow users to have a cohesive experience across all GitHub CLI commands, official or community-maintained, and so that more workflows can be made accessible by default. We’re also looking into experiences to customize the formatting of tables output by commands to be more easily read/interpreted by screen readers. We’re excited to continue our accessibility journey.

We couldn’t have come this far without collaboration with our friends at Charm and our colleagues on the GitHub Accessibility team. 

A call for feedback

We invite you to help us in our goal to make the GitHub CLI an experience for all developers:

  • Try it out: Update the GitHub CLI to v2.72.0 and run gh a11y in your terminal to learn more about enabling these new accessible features.
  • Share your experience: Join our GitHub CLI accessibility discussion to provide feedback or suggestions.
  • Connect with us: If you have a lived experience relevant to our accessibility personas, reach out to the accessibility team or get involved in our discussion panel.

Looking forward

Adapting accessibility standards for the command line is a challenge—and an opportunity. We’re committed to sharing our approach, learning from the community, and helping set a new standard for accessible CLI tools.

Thank you for building a more accessible GitHub with us.

Want to help us make GitHub the home for all developers? Learn more about GitHub’s accessibility efforts.

The post Building a more accessible GitHub CLI appeared first on The GitHub Blog.
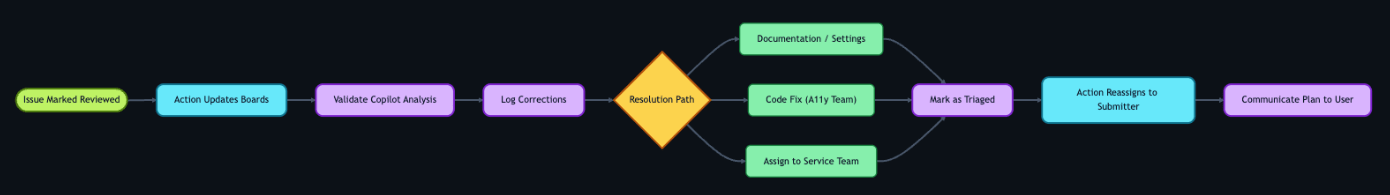
Considerations for making a tree view component accessible

Post Syndicated from Eric Bailey original https://github.blog/engineering/user-experience/considerations-for-making-a-tree-view-component-accessible/


Tree views are a core part of the GitHub experience. You’ve encountered one if you’ve ever navigated through a repository’s file structure or reviewed a pull request.

Browsing files on Primer's design repository. A tree view showing the repositories directory structure occupies a quarter of the screen. The other three quarters are taken up by the content of the content subdirectory. The tree view shows expanded and collapsed directories, as well as files nested at multiple levels of depth.

On GitHub, a tree view is the list of folders and the files they contain. It is analogous to the directory structure your operating system uses as a way of organizing things.

Tree views are notoriously difficult to implement in an accessible way. This post is a deep dive into some of the major considerations that went into how we made GitHub’s tree view component accessible. We hope that it can be used as a reference and help others.

Start with Windows

It’s important to have components with complex interaction requirements map to something people are already familiar with using. This allows for responsiveness to the keypresses they will try to navigate and take action on our tree view instances.

We elected to adopt Windows File Explorer’s tree view implementation, given the prominence of Windows’ usage for desktop screen reader users.

A Windows 11 File Explorer window showing a tree view and a list of subdirectories that one of its folders contains. The tree view demonstrates how the C drive contains multiple nested folders to organize its content.

Navigating and taking actions on items in Windows’ tree view using NVDA and JAWS helped us get a better understanding of how things worked, including factors such as focus management, keyboard shortcuts, and expected assistive technology announcements.

Then maybe reference the APG

The ARIA Authoring Practices Guide (APG) is a bit of an odd artifact. It looks official but is no longer recognized by the W3C as a formal document.

This is to say that the APG can serve as a helpful high-level resource for things to consider for your overall approach, but its suggestions for code necessitate deeper scrutiny.

Build from a solid, semantic foundation

At its core, a tree view is a list of lists. Because of this, we used ul and li elements for parent and child nodes:

<ul>
  <li>
    <ul>
      <li>.github/</li>
      <li>source/</li>
      <li>test/</li>
    </ul>
  </li>
  <li>.gitignore</li>
  <li>README.md</li>
</ul>

There are a few reasons for doing this, but the main considerations are:

  • Better assurance that a meaningful accessibility tree is generated,
  • Lessening the work we need for future maintenance, and consequential re-verification that our updates continue to work properly, and
  • Better guaranteed interoperability between different browsers, apps, and other technologies.

NOTE: GitHub currently does not virtualize its file trees. We would need to revisit this architectural decision if this ever changes.

Better broad assistive technology support

The more complicated an interactive pattern is, the greater the risk that there are bugs or gaps with assistive technology support.

Given the size of the audience GitHub serves, it’s important that we consider more than just majority share assistive technology considerations.

We found that utilizing semantic HTML elements also performed better for some less-common assistive technologies. This was especially relevant with some lower-power devices, like an entry-level Android smartphone from 2021.

Better Forced Color Mode support

Semantic HTML elements also map to native operating system UI patterns, meaning that Forced Color Mode’s heuristics will recognize them without any additional effort. This is helpful for people who rely on the mode to see screen content.

The heuristic mapping behavior does not occur if we used semantically neutral div or span elements, and would have to be manually recreated and maintained.

Use a composite widget

A composite widget allows a component that contains multiple interactive elements to only require one tab stop unless someone chooses to interact with it further.

Consider a file tree for a repository that contains 500+ files in 20+ directories. Without a composite widget treatment, someone may have to press Tab far too many times to bypass the file tree component and get what they need.

Think about wrapping it in a landmark

Like using a composite widget, landmark regions help some people quickly and efficiently navigate through larger overall sections of the page. Because of this, we wrapped the entire file tree in a nav landmark element.

This does not mean every tree view component should be a landmark, however! We made this decision for the file tree because it is frequently interacted with as a way to navigate through a repository’s content.

Go with a roving tabindex approach

A roving tabindex is a technique that uses tabindex="-1" applied to each element in a series, and then updates the tabindex value to use 0 instead in response to user keyboard input. This allows someone to traverse the series of elements, as focus “roves” to follow their keypresses.

<li tabindex="-1">File 1</li>
<li tabindex="-1">File 2</li>
<li tabindex="0">File 3</li>
<li tabindex="-1">File 4</li>

The roving tabindex approach performed better than utilizing aria-activedescendant, which had issues with VoiceOver on macOS and iOS.

Enhance with ARIA

We use a considered set of ARIA declarations to build off our semantic foundation.

Note that while we intentionally started with semantic HTML, there are certain ARIA declarations that are needed. The use of ARIA here is necessary and intentional, as it expands the capabilities of HTML to describe something that HTML alone cannot describe—a tree view construct.

Our overall approach follows what the APG suggests, in that we use the following:

  • role="tree" is placed on the parent ul element, to communicate that it is a tree view construct.
  • role="treeitem" is placed on the child li elements, to communicate that they are tree view nodes.
  • role="group" is declared on child ul elements, to communicate that they contain branch and leaf nodes.
  • aria-expanded is declared on directories, with a value of true to communicate that the branch node is in an opened state and a value of false to communicate that it is in a collapsed state instead.
  • aria-selected is used to indicate if branch or leaf nodes have been chosen by user navigation, and can therefore have user actions applied to them.

We also made the following additions:

  • aria-hidden="true" is applied to SVG icons (folders, files, etc.) to ensure its content is not announced.
  • aria-current="true" is placed on the selected node to better support when a node is deep linked to via URL.

NOTE: We use “branch node” and “leaf node” as broad terms that can apply to all tree view components we use on GitHub. For the file tree, branch nodes would correspond to directories and subdirectories, and leaf nodes would correspond to files.

Support expected navigation techniques

The following behaviors are what people will try when operating a tree view construct, so we support them:

Keyboard keypresses

  • Tab: Places focus on the entire tree view component, then moves focus to the next focusable item on the view.
  • Enter:
    • If a branch node is selected: Displays the directory’s contents.
    • If a leaf node is selected: Displays the leaf node’s contents.
  • Down: Moves selection to the next node that can be selected without opening or closing a node.
  • Up: Moves selection to the previous node that can be selected without opening or closing a node.
  • Right:
    • If a branch node is selected and in a collapsed state: Expands the selected collapsed branch node and does not move selection.
    • If a branch node is selected and in an expanded state: Moves selection to the directory’s first child node.
  • Left:
    • If a branch node is selected and in an expanded state: Collapses the selected collapsed directory node and does not move selection.
    • If a branch node is selected and in a collapsed state: Moves selection to the node’s parent directory.
    • If a leaf node is selected: Moves selection to the leaf node’s parent directory.
  • End: Moves selection to the last node that can be selected.
  • Home: Moves selection to the first node that can be selected.

We also support typeahead selection, as we are modeling Windows File Explorer’s tree view behaviors. Here, we move selection to the node closest to the currently selected node whose name matches what the user types.

Middle clicking

Nodes on tree view constructs are tree items, not links. Because of this, tree view nodes do not support the behaviors you get with using an anchor element, such as opening its URL in a new tab or window.

We use JavaScript to listen for middle clicks and Control+Enter keypresses to replicate this behavior.

Consider states

Loading

Tree views on GitHub can take time to retrieve their content, and we may not always know how much content a branch node contains.

A directory called, 'src' that is selected and in an expanded that. It contains a single leaf node that contains a loading spinner with a label of 'Loading…".

Live region announcements are tricky to get right, but integral to creating an equivalent experience. We use the following announcements:

  • If there is a known amount of nodes that load, we enumerate the incoming content with an announcement that reads, “Loading {x} items.”
  • If there is an unknown number of nodes that load, we instead use a more generic announcement of, “Loading…”
  • If there are no nodes that load we use an announcement message that reads, “{branch node name} is empty.”

Additionally, we manage focus for loading content:

  • If focus is placed on a placeholder loading node when the content loads in: Move focus from the placeholder node to the first child node in the branch node.
  • If focus is on a placeholder loading node but the branch node does not contain content: Move focus back to the branch node. Additionally, we remove the branch node’s aria-expanded declaration.

Errors

Circumstances can conspire to interfere with a tree view component’s intended behavior. Examples of this could be a branch node failing to retrieve content or a partial system outage.

In these scenarios, the tree view component will use a straightforward dialog component to communicate the error.

Fix interoperability issues

As previously touched on, complicated interaction patterns run the risk of compatibility issues. Because of this, it’s essential to test your efforts with actual assistive technology to ensure it actually works.

We made the following adjustments to provide better assistive technology support:

Use aria-level

Screen readers can report on the depth of a nested list item. For example, a li element placed inside of a ul element nested three levels deep can announce itself as such.

We found that we needed to explicitly declare the level on each li element to recreate this behavior for a tree view. For our example, we’d also need to set aria-level="3" on the li element.

This fix addressed multiple forms of assistive technology we tested with.

Explicitly set the node’s accessible name on the li element

A node’s accessible name is typically set by the text string placed inside the li element:

<li>README.md</li>

However, we found that VoiceOver on macOS and iOS did not support this. This may be because of the relative complexity of each node’s inner DOM structure.

We used aria-labelledby to get around this problem, with a value that pointed to the id set on the text portion of each node:

<li aria-labelledby="readme-md">
  <div>
   <!-- Icon -->
  </div>
  <div id="readme-md">
    README.md
  </div>
</li>

This guarantees that:

  • the node’s accessible name is announced when focus is placed on the li element,
  • and that the announcement matches what is shown visually.

Where we’d like to go from here

There’s a couple areas we’re prototyping and iterating on to better serve our users:

Browsers apply a lot of behaviors to anchor elements, such as the ability to copy the URL.

We’d like to replace the JavaScript that listens for middle clicks with a more robust native solution, only without sacrificing interoperability and assistive technology support.

Supporting multiple actions per node

Tree views constructs were designed assuming a user will only ever navigate to a node and activate it.

GitHub has use cases that require actions other than activating the node, and we’re exploring how to accomplish that. This is exciting, as it represents an opportunity to evolve the tree view construct on the web.

Always learning

An accessible tree view is a complicated component to make, and it requires a lot of effort and testing to get right. However, this work helps to ensure that everyone can use a core part of GitHub, regardless of device, circumstance, or ability.

We hope that highlighting the considerations that went into our work can help you on your accessibility journey.

Share your experience: We’d love to hear from you if you’ve run into issues using our tree view component with assistive technology. This feedback is invaluable to helping us continue to make GitHub more accessible.

The post Considerations for making a tree view component accessible appeared first on The GitHub Blog.
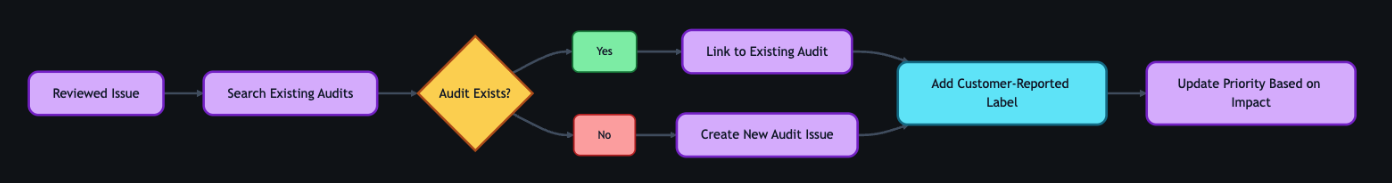
How to make Storybook Interactions respect user motion preferences

Post Syndicated from Kendall Gassner original https://github.blog/engineering/user-experience/how-to-make-storybook-interactions-respect-user-motion-preferences/


Recently, while browsing my company’s Storybook, I came across something that seemed broken: a flickering component that appeared to be re-rendering repeatedly. The open source tool that helps designers, developers, and others build and use reusable components was behaving weirdly. As I dug in, I realized I was seeing the unintended effects of the Storybook Interactions addon, which allows developers to simulate user interactions within a story, in action.

Storybook Interactions can be a powerful tool, enabling developers to simulate and test user behaviors quickly. But if you’re unfamiliar with Interactions—especially if you’re just looking to explore available components—the simulated tests jumping around on the screen can feel disorienting.

This can be especially jarring for users who have the prefers-reduced-motion setting enabled in their operating system. When these users encounter a story that includes an interaction, their preferences are ignored and they have no option to disable or enable it. Instead, the Storybook Interaction immediately plays on page load, regardless. These rapid screen movements can cause disorientation for users or in some cases can even trigger a seizure.

At this time, Storybook does not have built-in capabilities to toggle interactions on or off. Until this feature can be baked in I am hoping this blog will provide you with an alternative way to make your work environment more inclusive. Now, let’s get into building an addon that respects user’s motion preferences and allows users to toggle interactions on and off.

Goals

  1. Users with prefers-reduced-motion enabled MUST have interactions off by default.
  2. Users with prefers-reduced-motion enabled MUST have a way to toggle the feature on or off without altering their operating system user preferences.
  3. All users SHOULD have a way to toggle the feature on or off without altering their user preferences.

Let’s get started

Step 1: Build a Storybook addon

Storybook allows developers to create custom addons. In this case, we will create one that will allow users to toggle Interactions on or off, while respecting the prefers-reduced-motion setting.

Add the following code to a file in your project’s .storybook folder:

import React, {useCallback, useEffect} from 'react'

import {IconButton} from '@storybook/components'
import {PlayIcon, StopIcon} from '@storybook/icons'

export const ADDON_ID = 'toggle-interaction'
export const TOOL_ID = `${ADDON_ID}/tool`

export const INTERACTION_STORAGE_KEY = 'disableInteractions'

export const InteractionToggle = () => {
  const [disableInteractions, setDisableInteractions] = React.useState(
       window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === 'true',
  )

  useEffect(() => {
    const reducedMotion = matchMedia('(prefers-reduced-motion)')

    if (window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === null && reducedMotion.matches) {
      window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, 'true')
      setDisableInteractions(true)
    }
  }, [])

  const toggleMyTool = useCallback(() => {
    window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, `${!disableInteractions}`)
    setDisableInteractions(!disableInteractions)
      // Refreshes the page to cause the interaction to stop/start
      window.location.reload()
}, [disableInteractions, setDisableInteractions])

  return (
    <IconButton
      key={TOOL_ID}
      aria-label="Disable Interactions"
      onClick={toggleMyTool}
      defaultChecked={disableInteractions}
      aria-pressed={disableInteractions}
    >
      {disableInteractions ? <PlayIcon /> : <StopIcon />}
      Interactions
    </IconButton>
  )
}

Code breakdown

This addon stores user preferences for Interactions using window.localStorage. When the addon first loads, it checks whether the preference is already set and, if so, it defaults to the user’s preference.

const [disableInteractions, setDisableInteractions] = React.useState(
       window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === 'true',
  )

This useEffect hook checks if a user has their motion preferences set to prefers-reduced-motion and ensures that Interactions are turned off if the user hasn’t already set a preference in Storybook.

useEffect(() => {
    const reducedMotion = matchMedia('(prefers-reduced-motion)')

    if (window?.localStorage.getItem(INTERACTION_STORAGE_KEY) === null && reducedMotion.matches) {
      window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, 'true')
      setDisableInteractions(true)
    }
  }, [])

When a user clicks the toggle button, preferences are updated and the page is refreshed to reflect the changes.

const toggleMyTool = useCallback(() => {
    window?.localStorage?.setItem(INTERACTION_STORAGE_KEY, `${!disableInteractions}`)
    setDisableInteractions(!disableInteractions)
      // Refreshes the page to cause the interaction to stop/start
      window.location.reload()
  }, [disableInteractions, setDisableInteractions])

Step 2: Register your new addon with Storybook

In your .storybook/manager file, register your new addon:

addons.register(ADDON_ID, () => {
  addons.add(TOOL_ID, {
    title: 'toggle interaction',
    type: types.TOOL as any,
    match: ({ viewMode, tabId }) => viewMode === 'story' && !tabId,
    render: () => <InteractionToggle />,
  })
})

This adds the toggle button to the Storybook toolbar, which will allow users to change their Storybook Interaction preferences.

Step 3: Add functionality to check user preferences

Finally, create a function that checks whether Interactions should be played and add it to your interaction stories:

import {INTERACTION_STORAGE_KEY} from './.storybook/src/InteractionToggle'

export const shouldInteractionPlay = () => {
  const disableInteractions = window?.localStorage?.getItem(INTERACTION_STORAGE_KEY)
  return disableInteractions === 'false' || disableInteractions === null
}


 export const SomeComponentStory = {
  render: SomeComponent,
  play: async ({context}) => {
    if (shouldInteractionPlay()) {
...
    }
  })
 }

Wrap-up

With this custom addon, you can ensure your workplace remains accessible to users with motion sensitivities while benefiting from Storybook’s Interactions. For those with prefers-reduced-motion enabled, motion will be turned off by default and all users will be able to toggle interactions on or off.

The post How to make Storybook Interactions respect user motion preferences appeared first on The GitHub Blog.
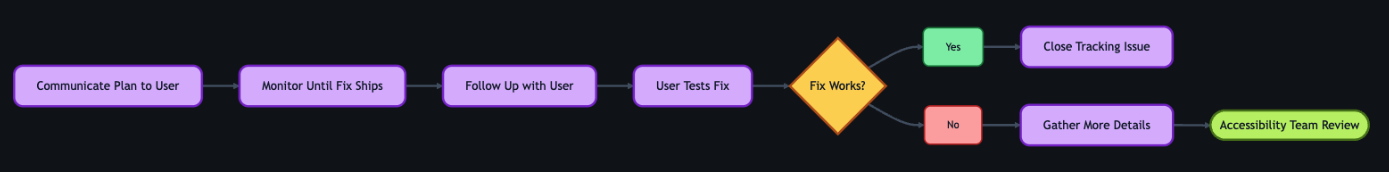
How GitHub supports neurodiverse employees (and how your company can, too)

Post Syndicated from Lou Nelson original https://github.blog/engineering/engineering-principles/how-github-supports-neurodiverse-employees-and-how-your-company-can-too/


In today’s global workplace, supporting employees by appreciating and understanding their background and lived experience is crucial for the success of any organization. This includes employees who are neurodivergent. Neurodivergence refers to natural variations in human brains and cognition. The term encompasses conditions such as autism, ADHD, dyslexia, mental illness, and other neurological differences.

Neurodivergent employees don’t just enrich the workplace, they’re good for business. According to Deloitte, teams with neurodivergent people can be up to 30 percent more productive than others. Neurodivergent folks excel in pattern recognition and the type of outside-the-box thinking highly sought after in the software industry.

In this blog post, we’ll take a look at five ways GitHub fosters and supports neurodiverse employees via Neurocats, a GitHub Community of Belonging (CoB), and how you can do the same at your organization.

Let’s go!

Two octocats (a cross between an octopus and a cat) attached at the head. One is the standard black GitHub mascot, the other is blue with lighter blue spots. They are smiling.

Forktocat: An Octocat image that represents the fork function in Git, which we’ve adopted in Neurocats to represent the different ways our brains work.

1. Establish supportive communities

As an initial step, establish private, supportive communities where neurodivergent employees can connect, share their experiences, and find support. GitHub’s Neurocats community allows members to privately discuss their neurodivergence, offer advice to each other, and build a sense of belonging, all in a safe place where members can freely express themselves without fear.

Neurocats started as a private Slack channel under a different name years before it formally transitioned into a CoB. Originally called #neuroconverse, it gave the neurodivergent community at GitHub a space to chat. In the summer of 2021, a collection of passionate members started discussions with GitHub’s Diversity Inclusion and Belonging team about becoming a formal CoB. In October 2021, they formed as an official group at GitHub, and after some discussion, became the Neurocats. The community now consists of hundreds of members from across the company and continues to grow.

Setting up spaces for neurodivergent individuals to express themselves and meet other like-minded friends and allies not only improves their overall work life balance, it also accelerates the creation of new innovative ideas that could be the next big thing in your organization’s portfolio.

“As a neurodivergent people manager with dyslexia and dysgraphia, I am thrilled to be part of the Neurocats CoB, a community that embraces and normalizes our uniqueness,” says Tina Barfield, senior manager at GitHub. “By doing so, we can help drive environments where everyone’s strengths are celebrated, leading to greater innovation, creativity, and inclusivity.” (Please note, all employee names and stories have been shared with permission.)

2. Foster a sense of belonging

Giving employees the time and space to discuss their neurodivergence enables them to strongly relate to each other, lift each other up, and make personal discoveries that will help them navigate life both at work and at home.

“I didn’t know what being neurodivergent was before Neurocats,” says Lou Nelson, support engineer III who works on GitHub Premium Support. “I thought I was a weird kid with an ADHD diagnosis. Neurocats has become the lynchpin for my career. I have made valuable connections and have a deeper insight into myself than I could have ever done alone. As a member, I find it incumbent to share this experience with others so that they also don’t have to feel alone.”

When neurodivergent employees feel comfortable enough to share their stories more broadly, other employees will be drawn to those communities to either personally relate or learn and empathize about subjects they may not have previously considered.

“As a people manager with ADHD, I’m accustomed to being the ‘neurodiversity pioneer’ when meeting new teams or direct reports, setting an example by speaking openly about my gifts and challenges,” says Julie Kang, staff manager of software engineering at GitHub. “When I joined GitHub, and especially when I became a Neurocat, I was pleasantly surprised to find a culture that was knowledgeable, accepting, and celebratory of neurodiversity at a level I haven’t seen before in my career.”

3. Provide flexibility and accommodations

Neurodivergent employees can often benefit from flexible working arrangements. This could include flexible hours, remote work options, noise-canceling headphones, or customized workspaces to reduce sensory overload.

Asking for accommodations can be hard. Identify the process your organization or company uses to assess workplace accommodations. Encourage employees to utilize that process to obtain a workplace accommodation.

“One of the biggest things for me has been seeing how many other folks went through a lot of their life being told that they just needed to apply themselves, pay attention, work harder, etc. only to repeatedly fail out of college, get fired from jobs, and generally struggle to ‘human’ correctly,” says Caite Palmer, manual review analyst of security operations at GitHub. “These folks are now through all departments and levels at this large, successful company getting to do great work in a place where flexibility, asking a million questions, and problem solving are generally considered tremendous assets and encouraged.”.

4. Encourage open dialogue

Promote a culture of openness where employees feel comfortable discussing their needs and challenges. Consider holding regular meetings and forums to discuss topics related to neurodiversity, mental health, and well-being. With the Neurocats group, we hold monthly meetings to discuss various topics, which are important to our members. One member of the Neurocats leadership team describes their experience:

“We have a voice, which we use to highlight issues our members face day to day,” says Owen Niblock, senior software engineer at GitHub who works on accessibility. “We also hold monthly meetings to discuss topics from ADHD and autism to anxiety, mental health issues, and more. Over the years, we’ve had some success and find we are able to lobby for changes at a company level, leading to real tangible change that benefits the whole of GitHub.”

Enabling open dialogue means providing avenues for these discussions to happen. But going one step further and encouraging open dialogue requires more effort.

5. Celebrate neurodiversity

Acknowledge and celebrate the unique contributions of neurodiverse employees. Recognize their achievements, provide opportunities for career advancement, and ensure they have a voice in the organization. Celebrating Disability Pride Month and other related events can help raise awareness and appreciation within the company.

“Neurocats was the first time I found people like me not only represented at work, but celebrated and successful,” Palmer says. “Sharing the rough days, the burnout, the overwhelm and frustration, but also the wins of finally getting appropriate support, being seen as creative instead of weird, and getting to learn about all the different ways brains can function.”

Celebrations should come not just from the community but also from leadership and the People Team. Sharing posts about the company’s mental health benefits during Mental Health Month (in May) or sharing information about the community during meetings or training can all help to celebrate your diverse workforce.

By implementing these strategies, you can create an inclusive environment where neurodivergent employees feel valued, supported, and empowered to contribute their best work.

“Neurocats provided an environment that made me feel safe and confident in an astonishingly short amount of time, allowing me to bring my A game, leverage my strengths, and make a positive impact much sooner than usual,” says Julie Kang, staff manager of software engineering at GitHub. “The support and understanding here have been truly transformative for my professional growth, and I feel equipped to pay this forward to my peers and reports.”

Interested in learning more about GitHub’s approach to accessibility? Visit accessibility.github.com.

The post How GitHub supports neurodiverse employees (and how your company can, too) appeared first on The GitHub Blog.
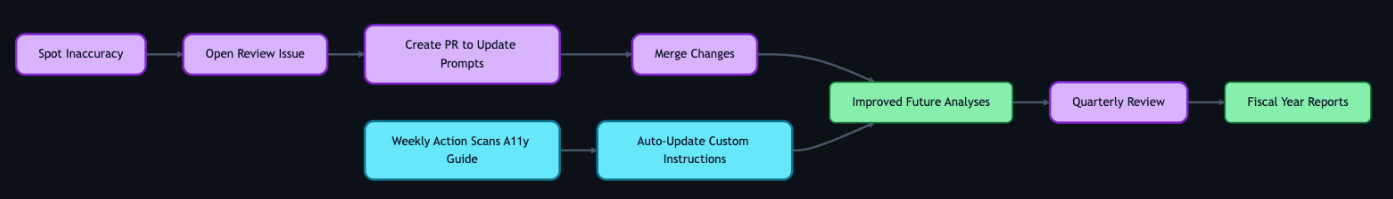
Exploring the challenges in creating an accessible sortable list (drag-and-drop)

Post Syndicated from Kendall Gassner original https://github.blog/engineering/user-experience/exploring-the-challenges-in-creating-an-accessible-sortable-list-drag-and-drop/

Drag-and-drop is a highly interactive and visual interface. We often use drag-and-drop to perform tasks like uploading files, reordering browser bookmarks, or even moving a card in solitaire. It can be hard to imagine completing most of these tasks without a mouse and even harder without using a screen or visual aid. This is why the Accessibility team at GitHub considers drag-and-drop a “high-risk pattern,” often leading to accessibility barriers and a lack of effective solutions in the industry.

Recently, our team worked to develop a solution for a more accessible sortable list, which we refer to as ‘one-dimensional drag-and-drop.’ In our first step toward making drag-and-drop more accessible, we scoped our efforts to explore moving items along a single axis.

An example of a sortable to do list. This list has  7 items all of which are in a single column. One of the the items is hovering over the list to indicate it is being dragged to another position.

Based on our findings, here are some of the challenges we faced and how we solved them:

Challenge: Screen readers use arrow keys to navigate through content

One of the very first challenges we faced involved setting up an interaction model for moving an item through keyboard navigation. We chose to use arrow keys as we wanted keyboard operation to feel natural for a visual keyboard user. However, this choice posed a problem for users who relied on screen readers to navigate throughout a webpage.

To note: Arrow keys are commonly used by screen readers to help users navigate through content, like reading text or navigating between cells in a table. Consequently, when we tested drag-and-drop with screen reader users, the users were unable to use the arrow keys to move the item as intended. The arrow keys ignored drag-and-drop actions and performed typical screen reader navigation instead.

In order to override these key bindings we used role='application'.

Take note: I cannot talk about using role='application' without also providing a warning. role='application' should almost never be used. It is important to use role='application' sparingly and to scope it to the smallest possible element. The role='application' attribute alters how a screen reader operates, making it treat the element and its contents as a single application.

Considering the mentioned caution, we applied the role to the drag-and-drop trigger to restrict the scope of the DOM impacted by role='application'. Additionally, we exclusively added role='application' to the DOM when a user activates drag-and-drop. We remove role='application' when the user completes or cancels out of drag-and-drop. By employing role='application', we are able to override or reassign the screen reader’s arrow commands to correspond with our drag-and-drop commands.

Remember, even if implemented thoughtfully, it’s crucial to rely on feedback from daily screen reader users to ensure you have implemented role='application' correctly. Their feedback and experience should be the determining factor in assessing whether or not using role='application' is truly accessible and necessary.

Challenge: NVDA simulates mouse events when a user presses Enter or Space

Another challenge we faced was determining whether a mouse or keyboard event was triggered when an NVDA screen reader user activated drag-and-drop.

When a user uses a mouse to drag-and-drop items, the expectation is that releasing the mouse button (triggering an onMouseUp event) will finalize the drag-and-drop operation. Whereas, when operating drag-and-drop via the keyboard, Enter or Escape is used to finalize the drag-and-drop operation.

To note: When a user activates a button with the Enter or Space key while using NVDA, the screen reader simulates an onMouseDown and onMouseUp event rather than an onKeyDown event.

Because most NVDA users rely on keyboard operations to operate drag-and-drop instead of a mouse, we had to find a way to make sure our code ignored the onMouseUp event triggered by an NVDA Enter or Space key press.

We accomplished this by using two HTML elements to separate keyboard and mouse functionality:
1. A Primer Icon button to handle keyboard interactions.
2. An invisible overlay to capture mouse interactions.

A screenshot of the drag-and-drop trigger. Added to the screenshot are two informational text boxes the first explains the purpose of the invisible overlay, stating:  "An empty <div> overlays the iconButton to handle mouse events. This is neither focusable nor visible to keyboard users. Associated event handlers: onMouseDown". The second text box explains the purpose of the visible iconButton, stating: "The iconButton can only be activated by keyboard users. This is not clickable for mouse users. Associated event handlers: onMouseDown, onKeyDown.

Challenge: Announcing movements in rapid succession

Once we had our keyboard operations working, our next big obstacle was announcing movements to users, in particular announcing rapid movements of a selected item.

To prepare for external user testing we tested our announcements ourselves with screen readers. Because we are not native screen reader users, we moved items slowly throughout the page and the announcements sounded great. However, users typically move items rapidly to complete tasks quickly, so our screen reader testing did not reflect how users would actually interact with our feature.

To note: It was not until user testing that we discovered that when a user moved an item in rapid succession the aria-live announcements would lag or sometimes announce movements that were no longer relevant. This would disorient users, leading to confusion about the item’s current position.

To solve this problem, we added a small debounce to our move announcements. We tested various debounce speeds with users and landed on 100ms to ensure that we did not slow down a user’s ability to interact with drag-and-drop. Additionally, we used aria-live='assertive' to ensure that stale positional announcements are interrupted by the new positional announcement.

export const debounceAnnouncement = debounce((announcement: string) => {
  announce(announcement, {assertive: true})
}, 100)

Take note: aria-live='assertive' is reserved for time-sensitive or critical notifications. aria-live='assertive' interrupts any ongoing announcements the screen reader is making and can be disruptive for users. Use aria-live='assertive' sparingly and test with screen reader users to ensure your feature implores it correctly.

Challenge: First-time user experience of a new pattern

To note: During user testing we discovered that some of our users found it difficult to operate drag-and-drop with a keyboard. Oftentimes, drag-and-drop is not keyboard accessible or screen reader accessible. As a result, users with disabilities might not have had the opportunity to use drag-and-drop before, making the operations unfamiliar to them.

This problem was particularly challenging to solve because we wanted to make sure our instruction set was easy to find but not a constant distraction for users who frequently use the drag-and-drop functionality.

To address this, we added a dialog with a set of instructions that would open when a user activated drag-and-drop via the keyboard. This dialog has a “don’t show this again” checkbox preference for users who feel like they have a good grasp on the interaction and no longer want a reminder.

A screenshot of the instruction dialog. The dialog contains a table with three rows. Each row contains two columns the first column is the movement and the second column is the keyboard command. At the bottom is the

Challenge: Moving items with voice control in a scrollable container

One of the final big challenges we faced was operating drag-and-drop using voice control assistive technology. We found that using voice control to drag-and-drop items in a non-scrollable list was straightforward, but when the list became scrollable it was nearly impossible to move an item from the top of the list to the bottom.

To note: Voice control displays an overlay of numbers next to interactive items on the screen when requested. These numbers are references to items a user can interact with. For example, if a user says, “Click item 5” and item 5 is a button on a web page the assistive technology will then click the button. These number references dynamically update as the user scrolls through the webpage. Because references are updated as a user scrolls, scrolling the page while dragging an item via a numerical reference will cause the item to be dropped.

We found it critical to support two modes of operation in order to ensure that voice control users are able to sort items in a list. The first mode of operation, traditional drag-and-drop, has been discussed previously. The second mode is a move dialog.

The move dialog is a form that allows users to move items in a list without having to use traditional drag-and-drop:

A screenshot of the Move Dialog. At the top of the dialog is a span specifying  the item being moved. Followed by a form to move items then a preview of the movement.

The form includes two input fields: action and position.
The action field specifies the movement or direction of the operation, for example, “move item before” or “move item after.” And the position specifies the location of where the item should be moved.

Below the input fields we show a preview of where an item will be moved based on the input values. This preview is announced using aria-live and provides a way for users to preview their movements before finalizing them.

During our testing we found that the move dialog was the preferred mode of operation for several of our users who do not use voice control assistive technology. Our users felt more confident when using the move dialog to move items and we were delighted to find that our accessibility feature provided unexpected benefits to a wide range of users.

In Summary, creating an accessible drag-and-drop pattern is challenging and it is important to leverage feedback and consider a diverse range of user needs. If you are working to create an accessible drag-and-drop, we hope our journey helps you understand the nuances and pitfalls of this complex pattern.

A big thanks to my colleagues, Alexis Lucio, Matt Pence, Hussam Ghazzi, and Aarya BC, for their hard work in making drag-and-drop more accessible. Your dedication and expertise have been invaluable. I am excited about the progress we made and what we will achieve in the future!

Lastly, if you are interested in testing the future of drag-and-drop with us, consider joining our Customer Research Panel.

The post Exploring the challenges in creating an accessible sortable list (drag-and-drop) appeared first on The GitHub Blog.
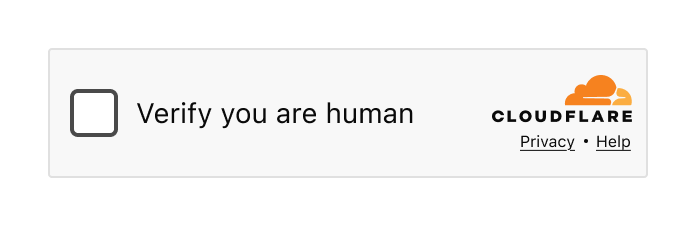
How we’re building more inclusive and accessible components at GitHub

Post Syndicated from Eric Bailey original https://github.blog/engineering/user-experience/how-were-building-more-inclusive-and-accessible-components-at-github/

One of GitHub’s core values is Diverse and Inclusive. It is a guiding thought for how we operate, reminding us that GitHub serves a developer community that spans a wide range of geography and ability.

Putting diversity and inclusivity into practice means incorporating a wide range of perspectives into our work. To that point, disability and accessibility are an integral part of our efforts.

This consideration has been instrumental in crafting resilient, accessible components at GitHub. These components, in turn, help to guarantee that our experiences work regardless how they are interacted with.

Using GitHub should be efficient and intuitive, regardless of your device, circumstance, or ability. To that point, we have been working on improving the accessibility of our lists of issues and pull requests, as well as our information tables.

Our list of issues and pull requests are some of the most high-traffic experiences we have on GitHub. For many, it is the “homepage” of their open source projects, a jumping off point for conducting and managing work.

Our tables help to communicate, and facilitate taking action with confidence on complicated information relationships. These experiences are workhorses, helping to communicate information about branches, repositories, secrets, attestations, configurations, internal documentation, etc.

Nothing about us without us

Before we discuss the particulars of these updates, I would like to call attention to the most important aspect of the work: direct participation of, and input from daily assistive technology users.

Disabled people’s direct involvement in the inception, design, and development stages is indispensable. It’s crucial for us to go beyond compliance and weave these practices into the core of our organization. Only by doing so can we create genuinely inclusive experiences.

With this context established, we can now talk about how this process manifests in component work.

Improvements we’re making to lists of issues and pull requests

A list of nine GitHub issues. The issues topics are a blend of list component work and general maintenance tasks. Each issue has a checkbox for selecting it, a status icon indicating that it is an open issue, a title, metadata about its issue number, author, creation date, and source repository. These issues also have secondary information including labels, tallies for linked pull requests and comments, avatars for issue assignees, and overflow actions. Additionally, some issues have a small badge that indicates the number of tasks the issue contains, as well as how many of them are completed. Above the list of issues is an area that lists the total number of issues, allows you to select them all, control how they are sorted, change the information display density, and additional overflow actions.

Lists of issues and pull requests will continue to support methods of navigation via assistive technology that you may already be familiar with—making experiences consistent and predictable is a huge and often overlooked aspect of the work.

In addition, these lists will soon be updated to also have:

  • A dedicated subheading for quickly navigating to the list itself.
  • A dedicated subheading per issue or pull request.
  • List and list item screen reader keyboard shortcut support.
  • Arrow keys and Home/End to quickly move through each list item.
  • Focus management that allows using Tab to explore individual list item content.
  • Support for Space keypresses for selecting list items, and Enter for navigating to the issue or pull request the list item links to.

This allows a wide range of assistive technologies to efficiently navigate, and act on these experiences.

Improvements we’re making to tables

A table titled, ‘Active branches’. It has five columns and 7 rows. The columns are titled ‘branches’, ‘updated’, ‘check status’, ‘behind/ahead’, ‘pull request’, and ‘actions’. Each row lists a branch name and its associated metadata. The branch names use a GitHub user name/feature name pattern. The user names include people who worked on the table component, including Mike Perrotti, Josh Black, Eric Bailey, and James Scholes. They also include couple of subtle references to disability advocates Alice Wong and Patty Berne. The branches are sorted by last updated order, and after the table is a link titled, ‘View more branches’.

We are in the process of replacing one-off table implementations with a dedicated Primer component.

Primer-derived tables help provide consistency and predictability. This is important for expected table navigation, but also applies for other table-related experiences, such as loading content, sorting and pagination requests, and bulk and row-level actions.

At the time of this blog post’s publishing, there are 75 bespoke tables that have been replaced with the Primer component, spread across all of GitHub.

The reason for this quiet success has been due entirely to close collaboration with both our disabled partners and our design system experts. This collaboration helped to ensure:

  1. The new table experiences were seamlessly integrated.
  2. Doing so, improved and enhanced the underlying assistive technology experience.

Progress over perfection

Meryl K. Evans’ Progress Over Perfection philosophy heavily influenced how we approached this work.

Accessibility is never done. Part of our dedication to this work is understanding that it will grow and change to meet the needs of the people who rely on it. This means making positive, iterative change based on feedback from the community GitHub serves.

More to come

Tables will continue to be updated, and the lists should be released publicly soon. Beyond that, we’re excited about the changes we’re making to improve GitHub’s accessibility. This includes both our services and also our internal culture.

We hope that these components, and the process that led to their creation, help you as both part of our developer community and as people who build the world’s software.

Please visit accessibility.github.com to learn more and share feedback on our accessibility community discussion page.

The post How we’re building more inclusive and accessible components at GitHub appeared first on The GitHub Blog.

Empowering accessibility: GitHub’s journey building an in-house Champions program

Post Syndicated from Carie Fisher original https://github.blog/engineering/engineering-principles/empowering-accessibility-githubs-journey-building-an-in-house-champions-program/

For more on this topic, check out Alexis Lucio, Catherine McNally, and Lindsey Wild‘s axe-con 2024 talk, “Establishing a Scalable A11y Education Ecosystem,” which laid the foundation for this blog post. Free registration required.

Laying the foundation

In today’s digital world, accessibility isn’t merely a checkbox—it’s the cornerstone of creating an inclusive experience for all users. At GitHub, we recognize this fundamental truth. That’s why we’ve embarked on a journey to empower developers, including those with disabilities, to participate fully and thrive on our platform. Our commitment to accessibility isn’t a one-time endeavor; it’s an ongoing effort fueled by the desire to remove barriers and make technology accessible to everyone.

As part of GitHub’s dedication to accessibility, we’ve been expanding our internal accessibility program and have scaled up our assessment process to help remove or lower barriers for users with disabilities. Naturally, as the number of assessments increased, so did the issues requiring attention, which strained our centralized accessibility team. Understanding the importance of decentralizing ownership of accessibility across the organization, we took decisive action by launching GitHub’s Accessibility Champions program. This strategic initiative empowers employees from various disciplines to drive accessibility efforts within their teams, fostering a culture where accessibility is deeply ingrained and valued.

The journey to establish GitHub’s Accessibility Champions program began with a comprehensive examination of our existing challenges and opportunities. We understood that for the program to thrive, we needed to consider various factors, including different time zones and work schedules, the expertise levels of our employees, and their ability to dedicate time to accessibility efforts due to competing priorities. By thoroughly assessing these considerations, we aimed to ensure that the program would be effective and adaptable to our team’s evolving needs.

To lay a solid foundation for the program’s success, we established clear goals and defined responsibilities for our champions upon completing their training. By setting measurable objectives and metrics to track the program’s impact on accessibility efforts both within the company and beyond, we provided our champions with a clear roadmap to follow. This proactive approach ensured we were all aligned in our efforts to make GitHub a more inclusive platform.

Starting small

At the heart of the GitHub Accessibility Champions program’s success is the development of a comprehensive and dynamic curriculum. Understanding that people have different learning preferences, GitHub took a tailored approach by assembling different types of educational resources. These resources were carefully curated to cater to various learning styles and delivered asynchronously through videos, articles, and interactive exercises.

Participants in the program received training on digital accessibility fundamentals, including WCAG guidelines, inclusive design principles, testing techniques, and content/interface accessibility best practices. They learned to identify and address accessibility barriers, advocate for accessibility within their teams, and utilize assistive technologies. Participants gained practical experience creating inclusive digital experiences through hands-on exercises and interactive discussions.

The program began with a modest group of 17 engineering champions serving as pioneers in the initiative. This small-scale pilot allowed GitHub to fine-tune the curriculum, gather valuable feedback, and iterate on the program’s structure and content. As the program evolved and gained momentum, it gradually expanded to include 52 champions from a variety of backgrounds, spanning engineering, design, and content teams. Our plan for this year is to reach over 100 internal champions to help support our accessibility goals.

This phased approach to scaling the GitHub Accessibility Champions program has proved invaluable. By starting small and gradually growing the community of champions, we were able to refine the program iteratively, ensuring it met the evolving needs of participants. Moreover, this approach fostered a strong sense of camaraderie among champions, creating a network of advocates dedicated to advancing accessibility across the organization.

Embracing feedback and iteration

Feedback was instrumental in shaping the trajectory of the GitHub Accessibility Champions program, serving as a guiding force in its evolution. As participants engaged with the program, their voices were invaluable in driving improvements and enhancements to meet their needs.

One recurring theme in the feedback was the desire for more interactive experiences and community engagement. Participants expressed a hunger for opportunities to connect with fellow champions, share insights, and collaborate on addressing accessibility challenges. In response, we introduced monthly Champions Connect meetings, providing a platform for champions to come together, exchange ideas, and foster a sense of camaraderie. These gatherings facilitated knowledge sharing and motivated and inspired champions as they navigated their accessibility journeys.

“Being able to ask questions and get answers quickly on simple matters is important to my team’s success. Or, if the questions are too complex to get immediate answers, having a forum to take the time and unpack them to get the answers.”

Participants also emphasized the importance of hands-on experiences in honing their skills and understanding of accessibility principles. Recognizing this need, we organized bug bashes and collaborative events where teams worked together to identify and address accessibility issues in real-time. These sessions provided practical learning opportunities and fostered a culture of teamwork and collective problem-solving.

In addition to enhancing engagement within the champions community, we responded to the demand for more synchronous training sessions. We hosted live sessions tailored to the specific needs of engineers and product managers, providing a platform for interactive discussions, Q&A sessions, and technical deep dives. These sessions offered a valuable opportunity for participants to engage directly with experts, seek clarification on complex topics, and deepen their understanding of accessibility best practices.

“Getting a codespace to identify issues and identify remediations is an excellent way to move from using and understanding assistive technology to taking on the role of an auditor or engineer who is verifying fixes.”

Finally, we initiated roundtable discussions with customers with disabilities, recognizing the importance of incorporating diverse perspectives into the design and development process. These interactions provided invaluable insights into the experiences and needs of users with disabilities, highlighting the critical role of inclusive design practices. By engaging directly with end-users, every champion at GitHub gained a deeper understanding of accessibility challenges and priorities, informing the development of more user-centric and inclusive digital experiences.

“Communicating the value of why we should design and create accessible documentation is key to success on my team. Everyone wants to do the right thing and is willing to do more complex tasks if they understand how it helps people better use our product.”

Overall, feedback catalyzed continuous improvement and innovation within the GitHub Accessibility Champions program. By actively listening to participant input and responding with targeted initiatives, we demonstrate our commitment to fostering a culture of accessibility and inclusion. Through ongoing engagement, collaboration, and user-centered design, GitHub continues to advance accessibility efforts, empowering all users to access and interact with its platform seamlessly.

“I loved that the training was super detailed, to a point where someone with zero information on accessibility can get started with basic concepts all the way to acknowledging problems they didn’t know existed.”

Expanding reach and impact

While we are proud of our progress so far, the GitHub Accessibility Champions program isn’t just about addressing internal challenges and setting an example for the broader tech community. By sharing our experiences and best practices, we hope to inspire other organizations to prioritize accessibility and inclusion in their own initiatives.

As we reflect on the journey of GitHub’s Accessibility Champions program, there are several key takeaways and future directions that can provide valuable insights for other teams and organizations embarking on similar initiatives:

  1. Start where you are. Take stock of your current situation and identify areas where accessibility education can be improved. Understanding your organization’s unique needs and challenges is the first step toward meaningful progress.
  2. Go where you’re wanted. Invest your resources with a clear advocacy for accessibility and a willingness to engage in educational programs. By aligning your efforts with enthusiastic stakeholders, you can maximize the impact of your initiatives.
  3. Pilot with a small group. Begin with a small group to test your programs and gather feedback before scaling up. This phased approach allows for experimentation and refinement, ensuring that your initiatives are effective and sustainable in the long run.
  4. Lean into organic partnerships. Collaborate across teams and titles to create a cohesive ecosystem of accessibility education. By leveraging the expertise and resources available within your organization, you can amplify the impact of your efforts and foster a culture of inclusivity.
  5. Seek out, review, and take action on feedback. Actively solicit feedback from participants and stakeholders and use it to inform program improvements. By listening to the needs and experiences of your audience, you can continuously iterate and enhance the effectiveness of your initiatives.
  6. Collect and re-evaluate metrics. Continuously monitor and evaluate the impact of your educational initiatives to track progress and effectiveness over time. By collecting meaningful metrics and analyzing trends, you can identify areas for improvement and demonstrate the value of your efforts to key stakeholders.

Conclusion

The GitHub Accessibility Champions program demonstrates our dedication to fostering a culture of accessibility and inclusion. By prioritizing feedback, collaboration, and responsiveness, we have created a supportive ecosystem where individuals can learn, grow, and acquire the tools to build more inclusive digital experiences. Our champions are truly a community of passionate accessibility advocates.

Looking ahead, we’re committed to enhancing the GitHub Accessibility Champions program, advancing accessibility efforts across the organization, and sharing our journey with the broader tech community—paving the way for a more inclusive digital future for all.

Please visit accessibility.github.com to learn more and to share feedback on our accessibility community discussion page.

The post Empowering accessibility: GitHub’s journey building an in-house Champions program appeared first on The GitHub Blog.
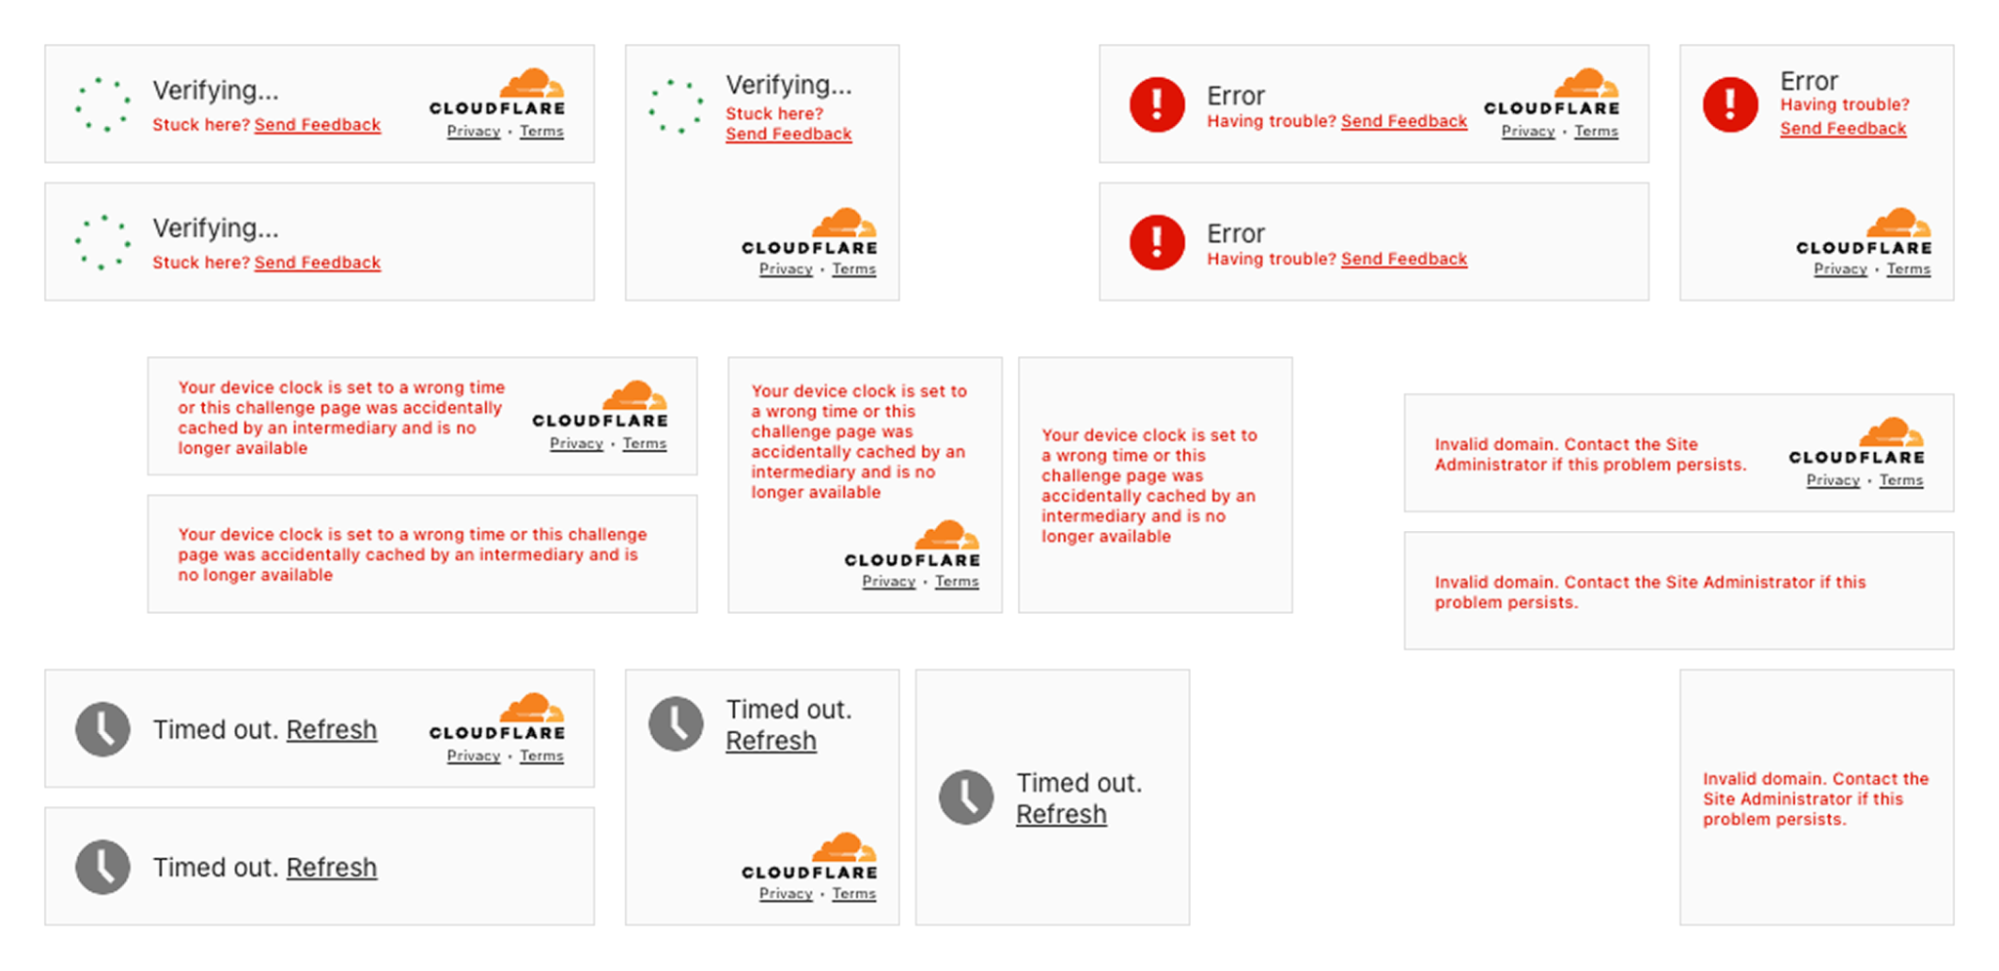
GitHub’s Engineering Fundamentals program: How we deliver on availability, security, and accessibility

Post Syndicated from Deepthi Rao Coppisetty original https://github.blog/2024-02-08-githubs-engineering-fundamentals-program-how-we-deliver-on-availability-security-and-accessibility/


How do we ensure over 100 million users across the world have uninterrupted access to GitHub’s products and services on a platform that is always available, secure, and accessible? From our beginnings as a platform for open source to now also supporting 90% of the Fortune 100, that is the ongoing challenge we face and hold ourselves accountable for delivering across our engineering organization.

Establishing engineering governance

To meet the needs of our increased number of enterprise customers and our continuing innovation across the GitHub platform, we needed to address tech debt, improve reliability, and enhance observability of our engineering systems. This led to the birth of GitHub’s engineering governance program called the Fundamentals program. Our goal was to work cross-functionally to define, measure, and sustain engineering excellence with a vision to ensure our products and services are built right for all users.

What is the Fundamentals program?

In order for such a large-scale program to be successful, we needed to tackle not only the processes but also influence GitHub’s engineering culture. The Fundamentals program helps the company continue to build trust and lead the industry in engineering excellence, by ensuring that there is clear prioritization of the work needed in order for us to guarantee the success of our platform and the products that you love.

We do this via the lens of three program pillars, which help our organization understand the focus areas that we emphasize today:

  1. Accessibility (A11Y): Truly be the home for all developers
  2. Security: Serve as the most trustworthy platform for developers
  3. Availability: Always be available and on for developers

In order for this to be successful, we’ve relied on both grass-roots support from individual teams and strong and consistent sponsorship from our engineering leadership. In addition, it requires meaningful investment in the tools and processes to make it easy for engineers to measure progress against their goals. No one in this industry loves manual processes and here at GitHub we understand anything that is done more than once must be automated to the best of our ability.

How do we measure progress?

We use Fundamental Scorecards to measure progress against our Availability, Security, and Accessibility goals across the engineering organization. The scorecards are designed to let us know that a particular service or feature in GitHub has reached some expected level of performance against our standards. Scorecards align to the fundamentals pillars. For example, the secret scanning scorecard aligns to the Security pillar, Durable Ownership aligns to Availability, etc. These are iteratively evolved by enhancing or adding requirements to ensure our services are meeting our customer’s changing needs. We expect that some scorecards will eventually become concrete technical controls such that any deviation is treated as an incident and other automated safety and security measures may be taken, such as freezing deployments for a particular service until the issue is resolved.

Each service has a set of attributes that are captured and strictly maintained in a YAML file, such as a service tier (tier 0 to 3 based on criticality to business), quality of service (QoS values include critical, best effort, maintenance and so on based on the service tier), and service type that lives right in the service’s repo. In addition, this file also has the ownership information of the service, such as the sponsor, team name, and contact information. The Fundamental scorecards read the service’s YAML file and start monitoring the applicable services based on their attributes. If the service does not meet the requirements of the applicable Fundamental scorecard, an action item is generated with an SLA for effective resolution. A corresponding issue is automatically generated in the service’s repository to seamlessly tie into the developer’s workflow and meet them where they are to make it easy to find and resolve the unmet fundamental action items.

Through the successful implementation of the Fundamentals program, we have effectively managed several scorecards that align with our Availability, Security, and Accessibility goals, including:

  • Durable ownership: maintains ownership of software assets and ensures communication channels are defined. Adherence to this fundamental supports GitHub’s Availability and Security.
  • Code scanning: tracks security vulnerabilities in GitHub software and uses CodeQL to detect vulnerabilities during development. Adherence to this fundamental supports GitHub’s Security.
  • Secret scanning: tracks secrets in GitHub’s repositories to mitigate risks. Adherence to this fundamental supports GitHub’s Security.
  • Incident readiness: ensures services are configured to alert owners, determine incident cause, and guide on-call engineers. Adherence to this fundamental supports GitHub’s Availability.
  • Accessibility: ensures products and services follow our accessibility standards. Adherence to this fundamental enables developers with disabilities to build on GitHub.
An example secret scanning scorecard showing 100% compliance for having no secrets in the repository, push protection enabled, and secret scanning turned on.
Example secret scanning scorecard

A culture of accountability

As much emphasis as we put on Fundamentals, it’s not the only thing we do: we ship products, too!

We call it the Fundamentals program because we also make sure that:

  1. We include Fundamentals in our strategic plans. This means our organization prioritizes this work and allocates resources to accomplish the fundamental goals we each quarter. We track the goals on a weekly basis and address the roadblocks.
  2. We surface and manage risks across all services to the leaders so they can actively address them before they materialize into actual problems.
  3. We provide support to teams as they work to mitigate fundamental action items.
  4. It’s clearly understood that all services, regardless of team, have a consistent set of requirements from Fundamentals.

Planning, managing, and executing fundamentals is a team affair, with a program management umbrella.

Designated Fundamentals champions and delegates help maintain scorecard compliance, and our regular check-ins with engineering leaders help us identify high-risk services and commit to actions that will bring them back into compliance. This includes:

  1. Executive sponsor. The executive sponsor is a senior leader who supports the program by providing resources, guidance, and strategic direction.
  2. Pillar sponsor. The pillar sponsor is an engineering leader who oversees the overarching focus of a given pillar across the organization as in Availability, Security, and Accessibility.
  3. Directly responsible individual (DRI). The DRI is an individual responsible for driving the program by collaborating across the organization to make the right decisions, determine the focus, and set the tempo of the program.
  4. Scorecard champion. The scorecard champion is an individual responsible for the maintenance of the scorecard. They add, update, and deprecate the scorecard requirements to keep the scorecard relevant.
  5. Service sponsors. The sponsor oversees the teams that maintain services and is accountable for the health of the service(s).
  6. Fundamentals delegate. The delegate is responsible for coordinating Fundamentals work with the service owners within their org, supporting the Sponsor to ensure the work is prioritized, and resources committed so that it gets completed.

Results-driven execution

Making the data readily available is a critical part of the puzzle. We created a Fundamentals dashboard that shows all the services with unmet scorecards sorted by service tier and type and filtered by service owners and teams. This makes it easier for our engineering leaders and delegates to monitor and take action towards Fundamental scorecards’ adherence within their orgs.

As a result:

  • Our services comply with durable ownership requirements. For example, the service must have an executive sponsor, a team, and a communication channel on Slack as part of the requirements.
  • We resolved active secret scanning alerts in repositories affiliated with the services in the GitHub organization. Some of the repositories were 15 years old and as a part of this effort we ensured that these repos are durably owned.
  • Business critical services are held to greater incident readiness standards that are constantly evolving to support our customers.
  • Service tiers are audited and accurately updated so that critical services are held to the highest standards.

Example layout and contents of Fundamentals dashboard

Tier 1 Services Out of Compliance [Count: 2]
Service Name Service Tier Unmet Scorecard Exec Sponsor Team
service_a 1 incident-readiness john_doe github/team_a
service_x 1 code-scanning jane_doe github/team_x

Continuous monitoring and iterative enhancement for long-term success

By setting standards for engineering excellence and providing pathways to meet through standards through culture and process, GitHub’s Fundamentals program has delivered business critical improvements within the engineering organization and, as a by-product, to the GitHub platform. This success was possible by setting the right organizational priorities and committing to them. We keep all levels of the organization engaged and involved. Most importantly, we celebrate the wins publicly, however small they may seem. Building the culture of collaboration, support, and true partnership has been key to sustaining the ongoing momentum of an organization-wide engineering governance program, and the scorecards that monitor the availability, security, and accessibility of our platform so you can consistently rely on us to achieve your goals.

Want to learn more about how we do engineering GitHub? Check out how we build containerized services, how we’ve scaled our CI to 15,000 jobs every hour using GitHub Actions larger runners, and how we communicate effectively across time zones, teams, and tools.

Interested in joining GitHub? Check out our open positions or learn more about our platform.

The post GitHub’s Engineering Fundamentals program: How we deliver on availability, security, and accessibility appeared first on The GitHub Blog.
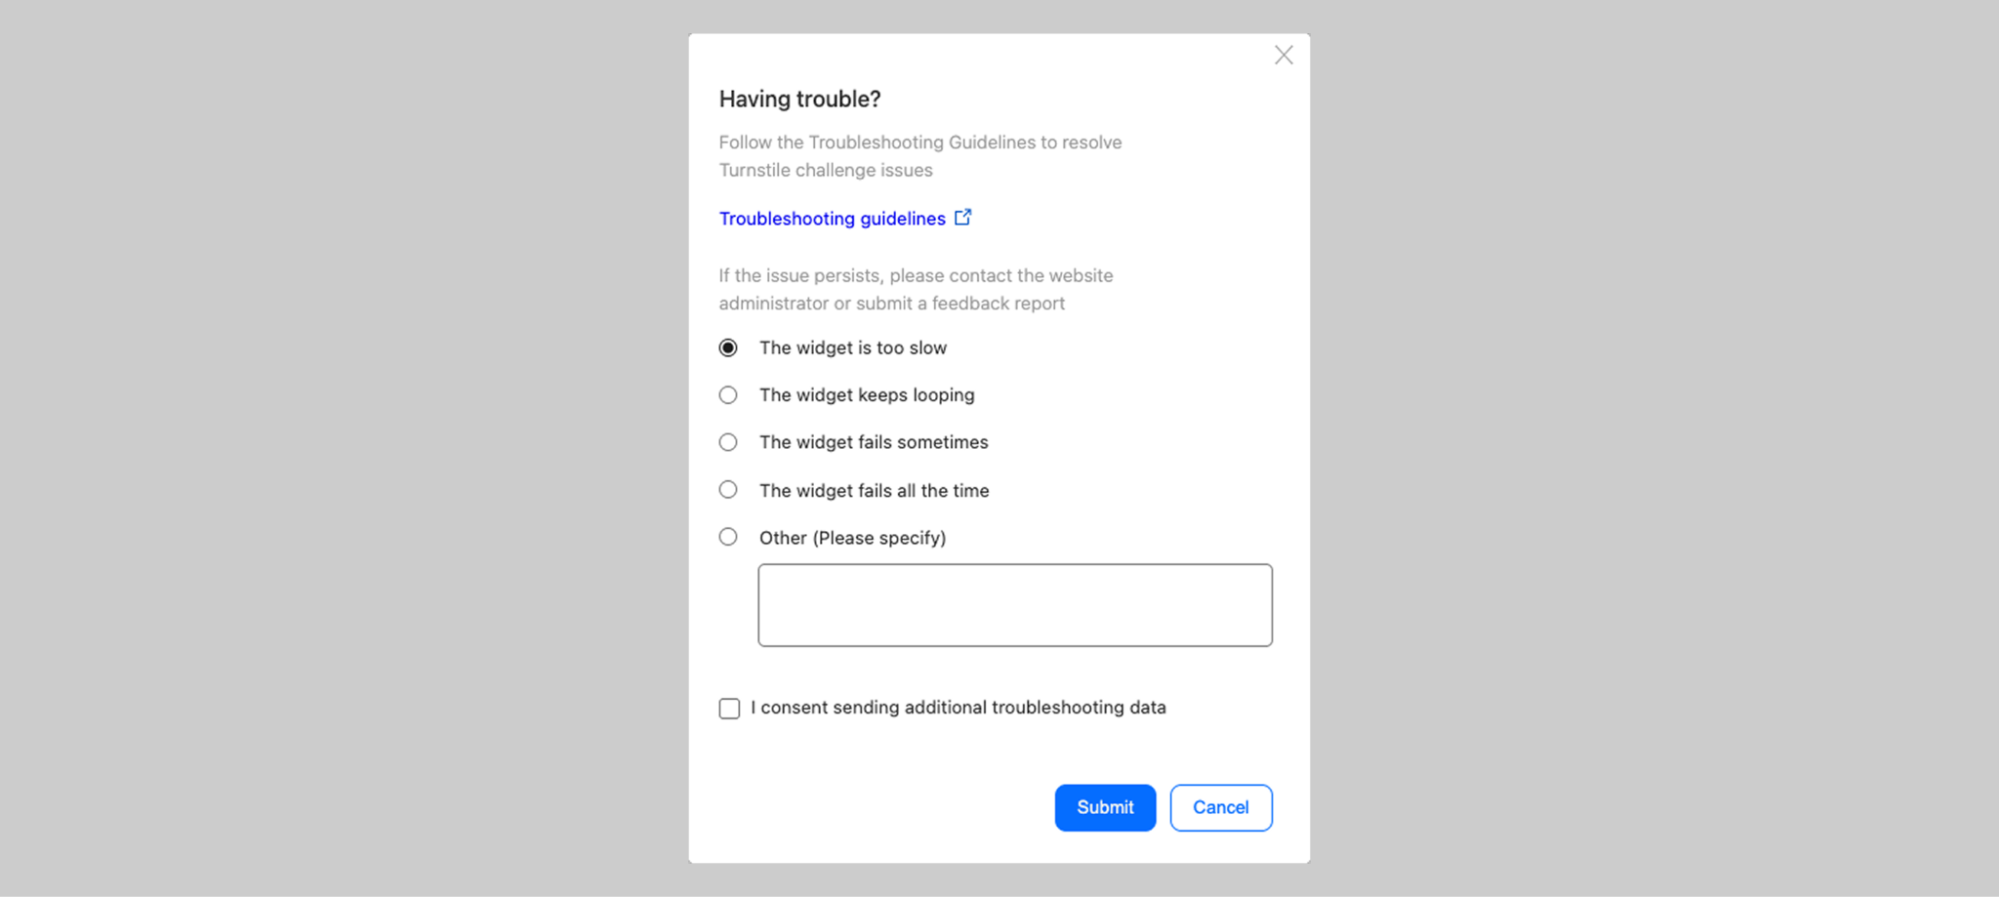
Prompting GitHub Copilot Chat to become your personal AI assistant for accessibility

Post Syndicated from Ed Summers original https://github.blog/2023-10-09-prompting-github-copilot-chat-to-become-your-personal-ai-assistant-for-accessibility/

Large Language Models (LLMs) are trained on vast quantities of data. As a result, they have the capacity to generate a wide range of results. By default, the results from LLMs may not meet your expectations. So, how do you coax an LLM to generate results that are more aligned with your goals? You must use prompt engineering, which is a rapidly evolving art and science of constructing inputs, also known as prompts, that elicit the desired outputs.

For example, GitHub Copilot includes a sophisticated built-in prompt engineering facility that works behind the scenes. It uses contextual information from your code, comments, open tabs within your editor, and other sources to improve results. But wouldn’t it be great to optimize results and ask questions about coding by talking directly to the LLM?

That’s why we created GitHub Copilot Chat. GitHub Copilot Chat complements the code completion capabilities of GitHub Copilot by providing a chat interface directly within your favorite editor. GitHub Copilot Chat has access to all the context previously mentioned and you can also provide additional context directly via prompts within the chat window. Together, the functionalities make GitHub Copilot a personal AI assistant that can help you learn faster and write code that not only meets functional requirements, but also meets non-functional requirements that are table stakes for modern enterprise software such as security, scalability, and accessibility.

In this blog, we’ll focus specifically on the non-functional requirement of accessibility. We’ll provide a sample foundational prompt that can help you learn about accessibility directly within your editor and suggest code that is optimized for better accessibility. We’ll break down the sample prompt to understand its significance. Finally, we’ll share specific examples of accessibility-related questions and results that demonstrate the power of prompting GitHub Copilot Chat to deliver results that improve accessibility. When using GitHub Copilot Chat, we recommend that you think of yourself as a lead developer who is working with a more junior developer (GitHub Copilot Chat). As the lead developer, it is your responsibility to verify information that is provided by GitHub Copilot Chat and ensure it meets all of your requirements.

Foundational accessibility prompt

You can copy this prompt and paste it directly into GitHub Copilot Chat for Visual Studio Code:

“I need to learn about accessibility and need to write code that conforms with the WCAG 2.1 level A and AA success criteria defined at https://www.w3.org/TR/WCAG21/. I want you to be my accessibility coach, a subject-matter expert that makes me think and account for all accessibility requirements and usability enhancements. When you answer questions about accessibility please use reputable sources such as w3.org, webaim.org, developer.mozilla.org, and https://www.ibm.com/able/. When possible, please provide links and references for additional learning. When you suggest code please use semantic HTML, ensure it is operable using the keyboard, follow WCAG 2.1 sufficient techniques, and follow the ARIA Authoring Practices Guide and related design patterns. Do you understand these instructions?”

What does this do?

This prompt can serve as your baseline in your codebase, whether you are just starting a project or in the thick of an extensive project.

The prompt consists of:

  1. Providing solid context and background information to help narrow down the scope of solutions.
  2. Defining GitHub Copilot’s role and setting expectations about what feedback we are looking for.
  3. Being specific in the quality of answers we are looking to reference from reputable sources.
  4. Asking for additional resources and context to learn more and ensure the answers we receive are correct. This helps provide feedback to GitHub Copilot.
  5. Dictating one final set of requirements to even further refine the scope based on the resources we have provided.

Note: At any time you can ask GitHub Copilot if it’s still referencing the foundation prompt you provided and it will inform you of its scope.

Query input: Are you still using the instructions I provided?
GitHub Copilot response: Yes, I am still adhering to the instructions you provided. I will continue to assist you in learning about accessibility and writing code that conforms with the WCAG 2.1 level A and AA success criteria. I will use reputable sources for references and additional learning, and ensure that the code suggestions I provide use semantic HTML, are operable using the keyboard, follow WCAG 2.1 sufficient techniques, and follow the ARIA Authoring Practices Guide and related design patterns.

Examples after the setting the foundation prompt

Note: These prompts were submitted in a brand new workspace that contained no source code or files to reference. Repeating these prompts in your codebase may produce different results as GitHub Copilot can use context provided from open tabs and existing files in the codebase. In addition, please keep in mind that results from LLMs are non-deterministic.

Accessibility testing

Query input: How can I test for web accessibility?
GitHub Copilot response: There are several ways to test for web accessibility:

  1. Manual Testing: This involves navigating your website using only a keyboard, checking color contrast, and resizing text to 200% to ensure readability.
  2. Automated Testing: There are several tools available for automated accessibility testing. Some popular ones include:
    1. WAVE: A free web accessibility evaluation tool provided by WebAIM.
    2. Axe: An accessibility testing toolkit built on a library of accessibility rules.
    3. Lighthouse: An open source, automated tool for improving the quality of web pages. It has audits for performance, accessibility, progressive web apps, SEO, and more.
  3. Screen Reader Testing: This involves testing your website using a screen reader tool. Some popular screen readers include NVDA, JAWS, and VoiceOver.
  4. User Testing: This involves testing your website with people with disabilities. This can provide valuable insights into how accessible your website is in practice.

Remember, no single tool or method can catch all accessibility issues, so a combination of methods is often the best approach.

For more information, you can refer to the following resources:

Tables

Query input: What are some best practices for creating accessible tables in HTML?
GitHub Copilot response: Creating accessible tables in HTML involves several best practices:

  1. Use <th> for table headers: This helps screen readers identify headers. Also, use the scope attribute to specify whether the header is for a row or a column.
    <table>
    <tr>
    <th scope="col">Header 1</th>
    <th scope="col">Header 2</th>
    </tr>
    <tr>
    <td>Data 1</td>
    <td>Data 2</td>
    </tr>
    </table>
    
  2. Provide captions: Use the <caption> element to provide a brief overview of the table. This is especially helpful for people using screen readers.
    <table>
    <caption>Overview of sales</caption>
    <!-- rest of the table -->
    </table>
    

    Use <thead>, <tbody>, and <tfoot>: These elements help to group different sections of the table and can improve accessibility.

    <table>
    <thead> <!-- header group -->
    <tbody> <!-- body group -->
    <tfoot> <!-- footer group -->
    </table>
    
  3. Avoid complex tables: If possible, avoid using tables for complex data structures. If you must, use rowspan and colspan attributes carefully and provide additional information in cell content or with the title attribute.

  4. Ensure readability without styles: The table should be readable and make sense even when styles are turned off.
  5. Use aria-labelledby for complex tables: If a table has multiple levels of headers, use the aria-labelledby attribute to associate data cells with headers.

For more information, you can refer to the WebAIM guide on creating accessible tables.

Forms

Query input: What are some best practices for creating accessible forms in HTML?
GitHub Copilot response: Creating accessible forms in HTML involves several best practices:

  1. Use <label> for form controls: Each form control should have a corresponding <label> element. This helps screen readers identify the purpose of the form control.
    <label for="name">Name:</label>
    <input id="name" name="name" type="text" />
    
  2. Group related form controls: Use the <fieldset> element to group related form controls and <legend> to provide a description for the group.
    <fieldset>
    <legend>Choose your favorite pet:</legend>
    <input type="radio" id="dog" name="pet">
    <label for="dog">Dog</label><br>
    <input type="radio" id="cat" name="pet">
    <label for="cat">Cat</label><br>
    </fieldset>
    
  3. Provide error messages and feedback: If the user makes an error, provide clear and specific feedback. Use the aria-describedby attribute to associate the form control with the error message.
    <input type="text" id="name" name="name" aria-describedby="nameError">
    <span id="nameError">Please enter your name.</span>
    
  4. Use correct input types: Use the correct input type for the form control (for example, email, number, date). This can provide the user with the appropriate keyboard on mobile devices.

  5. Make form controls keyboard accessible: Ensure that all form controls and buttons can be accessed and used with the keyboard.
  6. Use ARIA roles and properties when necessary: If a form control requires more complex interaction, use ARIA roles and properties to provide additional information to screen reader users.

For more information, you can refer to the WebAIM guide on creating accessible forms.

Keyboard support

Query input: What are some best practices for creating proper keyboard support in HTML?
GitHub Copilot response: Creating proper keyboard support in HTML involves several best practices:

  1. Logical Tab Order: Ensure that the tab order of the page follows the visual flow of the content. This can be achieved by structuring your HTML in a logical order. Avoid using positive tabindex values as they can disrupt the natural tab order.
  2. Keyboard Focus Indication: It’s important that users can visually identify which element currently has keyboard focus. This can be achieved using CSS to style the :focus state of interactive elements.
    button:focus, a:focus {
    outline: 2px solid blue;
    }
    
  3. Skip Links: Provide a mechanism to skip to main content or different sections of the page. This can be a link at the top of the page that becomes visible when it receives keyboard focus.
    <a href="#maincontent">Skip to main content</a>
    
  4. Accessible Interactive Elements: Ensure all interactive elements are accessible via keyboard. This includes links, buttons, form controls, and custom interactive widgets. Use semantic HTML elements whenever possible as they have built-in keyboard accessibility.

  5. Keyboard Support for Custom Widgets: If you’re creating custom interactive widgets (like a dropdown menu or modal dialog), you’ll need to provide additional keyboard support. This often involves handling keypress events for keys like Enter, Space, Escape, and the arrow keys. The WAI-ARIA Authoring Practices Guide provides detailed guidance on how to add keyboard support to various types of widgets.
  6. Avoid Keyboard Traps: Ensure that keyboard users can navigate to and from all parts of the page. Avoid situations where keyboard focus can be trapped in a particular page element.

For more information, you can refer to the WebAIM guide on keyboard accessibility.

Aria

Query input: What are some best practices around using proper ARIA roles in HTML?
GitHub Copilot response: ARIA (Accessible Rich Internet Applications) roles can be used to improve accessibility, especially when creating complex interactive elements. Here are some best practices:

  1. Use Semantic HTML First: Before using ARIA, consider whether you can use semantic HTML elements. These elements have built-in accessibility features that often make ARIA unnecessary. For example, use a <button> element instead of a <div> with a role="button".
  2. Don’t Change Native Semantics: Avoid using ARIA to change the semantics of native HTML elements. For example, don’t use role="button" on a link (<a>). Instead, use a <button> element.
  3. Use Appropriate Roles: When you do need to use ARIA, ensure you’re using the appropriate role for the element. The ARIA roles model provides a list of roles and their intended use.
  4. Provide Required States and Properties: Some roles require additional ARIA states or properties. For example, a checkbox requires the aria-checked state.
    <div role="checkbox" aria-checked="false">Check me</div>
    
  5. Use aria-labelledby and aria-describedby: These attributes can be used to provide additional descriptive text for an element.
    <button aria-describedby="info">More Info</button>
    <div id="info">Clicking this button will open more information.</div>
    
  6. Test with Screen Readers: After adding ARIA roles, test your page with a screen reader to ensure it’s providing the intended information.

Remember, ARIA should be used as a last resort when semantic HTML isn’t sufficient. The WAI-ARIA Authoring Practices Guide provides detailed guidance on how to use ARIA correctly.

Analysis

Reviewing the questions we asked GitHub Copilot, it suggested a lot of good information for us to learn more about best accessibility and usability practices. A few responses may be open to interpretation, while other responses lack details or specificity. Some examples include:

  • <tfoot> is an HTML element that calls attention to a set of rows summarizing the columns of the table. Including <tfoot> can help ensure the proper understanding of a table. However, not all tables require such rows–therefore, <tfoot> is not mandatory to have a usable table if the data doesn’t require it.
  • The response for the question about forms stressed the importance of the <label> element, which can help identify different labels for their various inputs. However, that response didn’t include any description about adding “for” attributes with the same value as the <input>’s ID. The response did include “for” attributes in the code suggestion, but an explanation about proper use of the “for” attribute would have been helpful.
  • The response to our question about keyboard accessibility included an explanation about interactive controls and buttons that can be accessed and used with a keyboard. However, it did not include additional details that could benefit accessibility such as ensuring a logical tab order, testing tab order, or avoiding overriding default keyboard accessibility for semantic elements.

If you are ever unsure of a recommendation or wish to know more, ask GitHub Copilot more questions on those areas, ask to provide more references/links, and follow up on the documentation provided. As a developer, it is your responsibility to verify the information you receive, no matter the source.

Conclusion

In our exploration, GitHub Copilot Chat and a well-constructed foundational prompt come together to create a personal AI assistant for accessibility that can improve your understanding of accessibility. We invite you to try the sample prompt and work with a qualified accessibility expert to customize and improve it.

Limitations and considerations

While clever prompts can improve the accessibility of the results from GitHub Copilot Chat, it is not reasonable to expect generative AI tools to deliver perfect answers to your questions or generate code that fully conforms with accessibility standards. When working with GitHub Copilot Chat, we recommend that you think of yourself as a lead developer who is working with a more junior developer. As the lead developer, it is your responsibility to verify information that is provided by GitHub Copilot Chat and ensure it meets all of your requirements. We also recommend that you work with a qualified accessibility expert to review and test suggestions from GitHub Copilot. Finally, we recommend that you ensure that all GitHub Copilot Chat code suggestions go through proper code review, code security, and code quality channels to ensure they meet the standards of your team.

Learn more

The post Prompting GitHub Copilot Chat to become your personal AI assistant for accessibility appeared first on The GitHub Blog.

Accessibility considerations behind code search and code view

Post Syndicated from milemons original https://github.blog/2023-07-06-accessibility-considerations-behind-code-search-and-code-view/

GitHub prides itself on being the home for all developers, including developers with disabilities. Accessibility is a core priority for all new projects at GitHub, so it was top of mind when we started our project to rework code search and the code view at GitHub. With the old code view, some developers preferred to look at raw code rather than code view due to accessibility barriers, and that’s what we set out to fix. This blog post will shed light on our process and three major tasks that required thoughtful design and implementation—code search and query builder, the file tree, and navigating code by keyboard.

Process

We worked with a team of experts at GitHub dedicated to accessibility, since while we are confident in our development skills, accessibility has many nuances and requires a large depth of knowledge to get right. This team helped us immensely in three main ways:

  1. External auditing
    In this project, we performed accessibility auditing on all of our features. This meant that another team of auditors reviewed our webpage with all the changes implemented to find accessibility errors. They used tools including screen readers, color contrast tools, and more, to identify areas that users with disabilities may find hard to use. Once those issues were identified, the accessibility team would take a look at those issues and suggest a proper solution to the problem. Then, it was up to us to implement the solution and collaborate with the team where we needed additional assistance.
  2. Design reviews
    The user interface for code search and code view were both entirely redesigned to support our new goals—to allow users to search, navigate, and understand code in a way they weren’t able to before. As a part of the design process, a team of accessibility designers reviewed the Figma mockups to determine proper HTML markup and tab order. Then, they included detailed explanations of what interactions should look like in order to meet our accessibility goals.
  3. Office hours
    The accessibility team at GitHub hosts weekly meetings where engineers can sign up and discuss how to solve problems with their features with the team and a consultant. The consultant is incredibly helpful and knowledgeable about how to properly address issues because he has lived experience with screen readers and accessibility.During these meetings, we were able to discuss complicated issues, such as the following: proper filtering for code search, making an accessible file tree, and navigating code on a keyboard, along with other issues like tab order, and focus management across the whole feature.

Implementation details

This has been written about frequently on our blog—from one post on the details of QueryBuilder, our implementation of an accessible finder component to details about what navigating code search accessibly looks like. Those two posts are great reads and I strongly recommend checking them out, but they’re not the only thing that we’ve worked on. Thanks to @lindseywild, @smockle, @kendallgassner, @owenniblock, and @khiga8 for their guidance and help resolving issues with code search. This is still a work in progress, especially in areas like the filtering behavior on the search pages.

Two areas that also required careful consideration were managing focus after changing the sort order of search results and how to announce the result of the search for screen reader users.

Changing sort—changing focus?

When we first implemented this sort dropdown for non-code search types, if you navigated to it with your keyboard and then selected a different sort option, the whole page would reload and your focus moved back to the header. Our preferred, accessible behavior is that, when a dropdown menu is closed, focus returns to the button that opened the menu. However, our problem was that the “Sort” dropdown didn’t merely perform client-side operations like most dropdowns where you select an option. In this case, once a user selects an option, we do a full page navigation to perform the new search with the sort order added. This meant that the focus was being placed back on the header by default after the page navigation, instead of returning to the sort dropdown. For sighted mouse users, this is a nonissue; for sighted keyboard users, it is unexpected and annoying; for blind users, this is confusing and makes the product hard to use. To fix this, we had to make sure we returned focus to the dropdown after reloading the page.

Screenshot of search results. I have searched “react” and the “Repositories” filter by item is selected. There are 2.2M results, found in 1 second. The "Sort By" dropdown is open with “Best match” selected. The other options are “Most stars”, “Fewest stars”, “Most forks”, “Fewest forks”, “Recently updated”, and “Least recently updated”.

Announcing search results

When a sighted user types in the search bar and presses ‘Enter’ they quickly receive feedback that the search has completed and whether or not they found any results by looking at the page. For screen reader users, though, how to give the feedback that there were results, how many, or if there was an error requires more thought. One solution could be to place focus on the first result. That has a number of problems though.

  1. The user will not receive feedback about the number of search results and may think there’s only one.
  2. The user may miss important context like the Single sign on banner.
  3. The user will have to tab through more elements if they want to get back.

Another solution could be to use aria-live announcements to read out the number of results and success. This has its own problems.

  1. We already have an announcement on page navigation to read out the new title and these two announcements would compete or cause a race condition.
  2. There isn’t a way to programmatically force announcements to be read in order on page load.
  3. Some screen reader users have aria-live announcements turned off since they can be annoying.
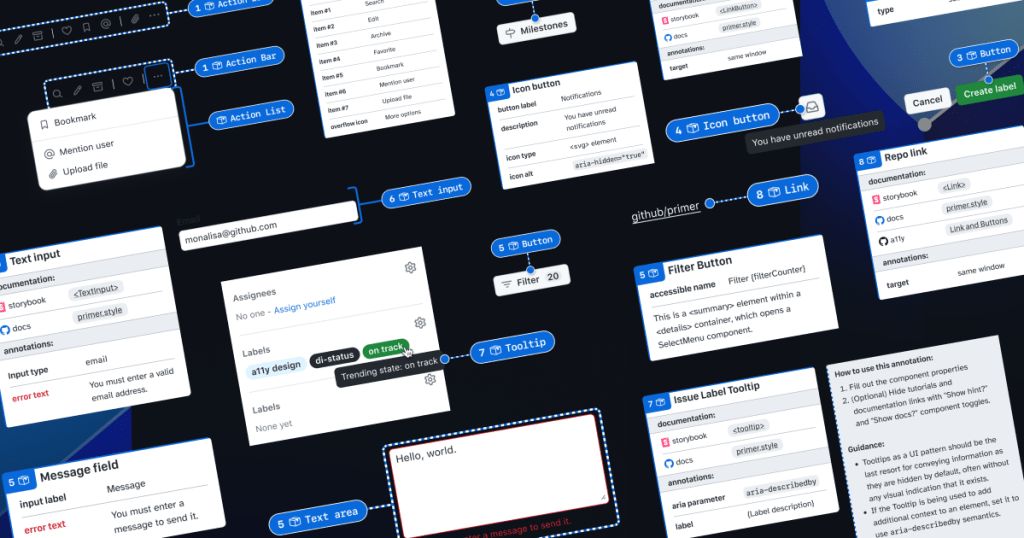
After some discussion, we decided to focus and read out the header with the number of search results after a search and allow users to explore for errors, banners, or results on their own once they know how many results they received.
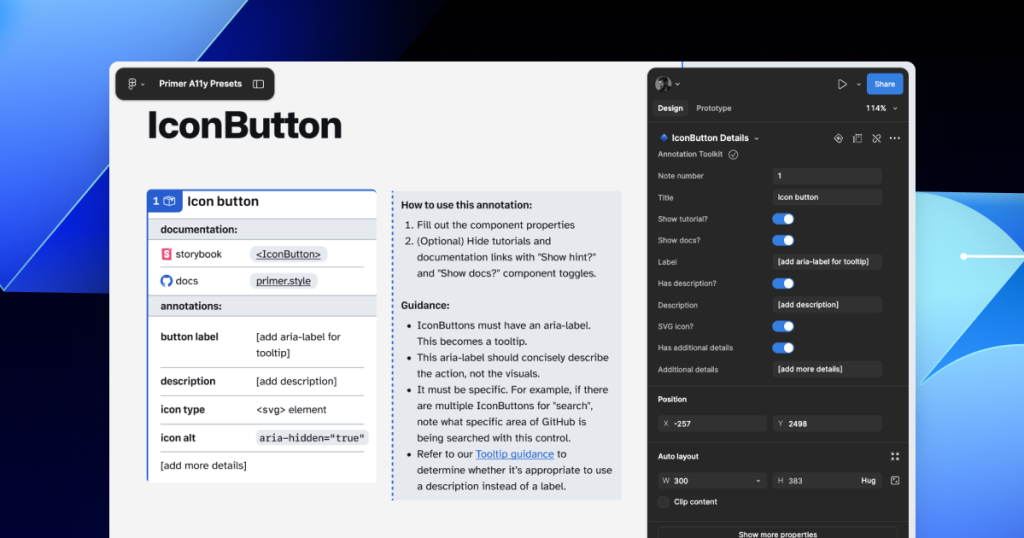
A screenshot of search results showing 0 results and an error message saying, “Invalid repository name.” I have searched “repo:asdfghijkl." The “Code” filter item is selected. There is also some help text on the page that says “Your search did not match any code. However, we found 544k packages that matched your search query. Alternatively, try one of the tips below.

Tree navigation

We knew when redesigning the code viewing experience that we wanted to include the tree panel to allow users to quickly switch between folders or files, because understanding code often requires looking in multiple places. We started the project by making our own tree to the aria spec, but it was too verbose. To fix this, our accessibility and design teams created the TreeView, which is open source. This was implemented to support various generic list elements and use proper HTML structure to make navigating through the tree a breeze, including typeahead (the ability to type a bit and have focus move to the first matching element), proper announcements for asynchronous loading of deeply nested items, and proper IDs for all elements that are guaranteed to be unique (that is, not constructed from their contents which may be the same). The valid markup for a tree view is very specific and developing it requires careful reviews for common issues, like invalid child item types under a role="group" element or using nested list elements without considering screen reader support, which is unlike most TreeView implementations on the internet. For more information about the design details for the tree view, check out the markdown documentation. Thanks to @colebemis, @mperrotti, and @ericwbailey for the work on this.

Reading and navigating code by keyboard

Before the new code view, reading code on GitHub wasn’t a great experience for screen reader users. The old experience presented code as a table—a hidden detail for sighted users but a major hurdle for screen readers, since code isn’t a table, and the semantics didn’t make sense in that context. For example, in code, whitespace has meaning. Whether stylistic or functional, that whitespace gets lost for screen reader users when the code is presented as a table. In addition, table semantics force users into line-by-line navigation, instead of character-by-character or word-by-word navigation. For many users, these hurdles meant that they mostly used GitHub just enough to be able to access the raw code or use a code editor for reading code. Since we want to support all our users, we knew we needed to totally rethink the way we structured code in the DOM.

This problem became even more complicated when we introduced symbols and the symbols panel. Mouse users are able to click on a “symbol” in the code—a special code element, like a function name—to see extra details about it, including references and definitions, in the symbol panel. They can then explore the code more deeply, navigating between lines of code where that symbol is found to investigate and understand the code better. This ability to dive deep has been game changing for many developers. However, for keyboard users, it doesn’t work. At best, a keyboard user can use the “Open symbols panel” button in the code header and then filter all symbol definitions for one they are interested in, but this doesn’t allow users to access symbol references when no definitions are found in a file. In addition, this flow really isn’t the same—if we want to support all developers, then we need to offer keyboard users a way to navigate through the code and select symbols they are interested in.

In addition, for many performance reasons mentioned in the post “Crafting a better, faster code view,” we introduced virtualization to the code viewer which created its own accessibility problems—not having all elements in the DOM can interfere with screen readers and overriding the cmd / ctrl + f shortcut is generally bad practice for screen readers as well. In addition, virtualization posed a problem for selecting text outside of the virtualization window.

This is when we came up with the solution of using a cursor from a <textarea> or a <div> that has the property contentEditable. This solution is modeled after Monaco, the text editor that powers VS Code. <textarea> elements, when not marked as readOnly, and contentEditiable<div> elements have a built in cursor that allows screen reader users to navigate code in their preferred manner using their built in screen reader settings. While a contentEditiable <div> would support syntax highlighting and the deep interactions we needed, screen readers don’t support them well1 which defeats the purpose of the cursor. As a result, we decided to go with the <textarea> However, <textarea> elements do not support syntax highlighting or deeper interactions like selecting symbols, which meant we needed to use both the <textarea> as a hidden element and syntax highlighted elements aligned perfectly above. Since we hide the text element, we need to add a visual “fake” cursor to show and keep it in sync with the “real” <textarea> cursor.

While the <textarea> and cursor help with our goals of allowing screen reader users and keyboard users to navigate code and symbols easily, they also ended up helping us with some of the problems we had run into with virtualization. One example of this was the cmd + f problem that we talk about more in depth in the blog post here. Another problem this solved was the drag and select behavior (or select all) for long files. Since the <textarea> is just one DOM node, we are able to load the whole file contents and select the contents directly from the <textarea> instead of the virtualized syntax highlighted version.

Unfortunately, while the <textarea> solved many problems we had, it also introduced a few other tricky ones. Since we have two layers of text, one hidden unless selected and one visual, we need to make sure that the scroll states are aligned. To do this, we have written observers to watch when one scrolls and mimic the scroll on the other. In addition, we often need to override the default <textarea> behaviors for some events—such as the middle click on mouse which was taking users all the way to the bottom of the code. Along with that issue, different browsers handle <textarea>s differently and making sure our solution behaves properly on all browsers has proven to be time intensive to say the least. In addition, we found that some browsers, like Firefox, allow users to customize their font size using Text zoom, which would apply to the formatted text but not the <textarea>. This led to “ghost text” issues with selection. We were able to resolve that by measuring the height of the text that is rendered and passing that to the <textarea>, though there are still some issues with certain plugins that modify text. We are still working to resolve these specific issues as well. In addition, the <textarea> currently does not work with our Wrap lines view option, which we are working to fix. Thanks especially to @joycezhu, @andrialexandrou, @adamshwert, and @jbrown1618 who put in a ton of work here.

Always iterating

We have taken huge strides to improve accessibility for all developers, but we recognize that we aren’t all the way there. It can be challenging to accommodate all developers, but we are committed to improving and iterating on what we have until we get it right. We want our tools to support everyone to access and explore code. We still have work—a lot of work—to do across GitHub, but we are excited for this journey.

To learn more about accessibility at GitHub, go to accessibility.github.com.


  1. For more information about contentEditable and screen readers, see this article written by @joycezhu from our Accessibility Engineering team. 

GitHub celebrates developers with disabilities on Global Accessibility Awareness Day

Post Syndicated from Ed Summers original https://github.blog/2023-05-18-github-celebrates-developers-with-disabilities-on-global-accessibility-awareness-day/

At GitHub, our favorite people are developers. We love to make them happy and productive, and today, on Global Accessibility Awareness Day, we want to celebrate their achievements by sharing some great stories about a few developers with disabilities alongside news of recent accessibility improvements at GitHub that help them do the best work of their lives.

Amplifying the voices of disabled developers

People with disabilities frequently encounter biases that prevent their full and equal participation in all areas of life, including education and employment. That’s why GitHub and The ReadME Project are thrilled to provide a platform for disabled developers to showcase their contributions and counteract bias.

Paul Chiou, a developer who’s paralyzed from the neck down, is breaking new ground in the field of accessibility automation, while pursuing his Ph.D. Paul uses a computer with custom hardware and software he designed and built, and this lived experience gives him a unique insight into the needs of other people with disabilities. The barriers he encounters push him to innovate, both in his daily life and in his academic endeavors. Learn more about Paul and his creative solutions in this featured article and video profile.

Becky Tyler found her way to coding via gaming, but she games completely with her eyes, just like everything else she does on a computer, from painting to livestreaming to writing code. Her desire to play Minecraft led her down the path of open source software and collaboration, and now she’s studying computer science at the University of Dundee. Learn more about Becky in this featured article and video profile.

Dr. Annalu Waller leads the Augmentative and Alternative Communication Research Group at the University of Dundee. She’s also Becky’s professor. Becky calls her a “taskmaster,” but the profile of Annalu’s life shows how her lived experience informed her high expectations for her students—especially those with disabilities—and gave her a unique ability to absorb innovations and use them to benefit people with disabilities.

Anton Mirhorodchenko has difficulty speaking and typing with his hands, and speaks English as a second language. Anton has explored ways to use ChatGPT and GitHub Copilot to not only help him communicate and express his ideas, but also develop software from initial architecture all the way to code creation. Through creative collaboration with his AI teammates, Anton has become a force to be reckoned with, and he recently shared his insights in this guide on how to harness the power of generative AI for software development.

Removing barriers that block disabled developers

Success requires skills. That’s why equal access to education is a fundamental human right. The GitHub Global Campus team agrees. They are working to systematically find and remove barriers that might block future developers with disabilities.

npm is the default package manager for JavaScript and the largest software registry in the world. To empower every developer to contribute to and benefit from this amazing resource, the npm team recently completed an accessibility bug bash and removed hundreds of potential barriers. Way to go, npm team!

The GitHub.com team has also been hard at work on accessibility and they recently shipped several improvements:

Great accessibility starts with design, requiring an in-depth understanding of the needs of users with disabilities and their assistive technologies. The GitHub Design organization has been leaning into accessibility for years, and this blog post explores how it has built a culture of accessibility and shifted accessibility left in the GitHub development process.

When I think about the future of technology, I think about GitHub Copilot—an AI pair programmer that boosts developers’ productivity and breaks down barriers to software development. The GitHub Copilot team recently shipped accessibility improvements for keyboard-only and screen reader users.

GitHub Next, the team behind GitHub Copilot, also recently introduced GitHub Copilot Voice, an experiment currently in technical preview. GitHub Copilot Voice empowers developers to code completely hands-free using only their voice. That’s a huge win for developers who have difficulty typing with their hands. Sign up for the technical preview if you can benefit from this innovation.

Giving back to our community

As we work to empower all developers to build on GitHub, we regularly contribute back to the broader accessibility community that has been so generous to us. For example, all accessibility improvements in Primer are available for direct use by the community.

Our accessibility team includes multiple Hubbers with disabilities—including myself. GitHub continually improves the accessibility and inclusivity of the processes we use to communicate and collaborate. One recent example is the process we use for retrospectives. At the end of our most recent retrospective, I observed that, as a person with blindness, it was the most accessible and inclusive retrospective I have ever attended. That observation prompted the team to share the process we use for inclusive retrospectives so other teams can benefit from our learnings.

More broadly, Hubbers regularly give back to the causes we care about. During a recent social giving event, I invited Hubbers to support the Seeing Eye because that organization has made such a profound impact in my life as a person with blindness. Our goal was to raise $5,000 so we could name and support a Seeing Eye puppy that will eventually provide independence and self-confidence to a person with blindness. I was overwhelmed by the generosity of my coworkers when they donated more than $15,000! So, we now get to name three puppies and I’m delighted to introduce you to the first one. Meet Octo!

A German Shepard named Octo sits in green grass wearing a green scarf that says “The Seeing Eye Puppy Raising Program.” She is sitting tall in a backyard with a black fence and a red shed behind her.
Photo courtesy of The Seeing Eye

Looking ahead

GitHub CEO, Thomas Dohmke, frequently says, “GitHub thrives on developer happiness.” I would add that the GitHub accessibility program thrives on the happiness of developers with disabilities. Our success is measured by their contributions. Our job is to remove barriers from their path and celebrate their accomplishments. We’re delighted with our progress thus far, but we are just getting warmed up. Stay tuned for more great things to come! In the meantime, learn more about the GitHub accessibility program at accessibility.github.com.

Creating an accessible search experience with the QueryBuilder component

Post Syndicated from Lindsey Wild original https://github.blog/2022-12-13-creating-an-accessible-search-experience-with-the-querybuilder-component/

Overview

Throughout the GitHub User Interface (UI), there are complex search inputs that allow you to narrow the results you see based on different filters. For example, for repositories with GitHub Discussions, you can narrow the results to only show open discussions that you created. This is completed with the search bar and the use of defined filters. The current implementation of this input has accessibility considerations that need to be examined at a deeper level, from the styled search input to the way items are grouped, that aren’t natively accessible, so we had to take some creative approaches. This led us to creating the QueryBuilder component, which is a fully accessible component designed for these types of situations.

As we rethought this core pattern within GitHub, we knew we needed to make search experiences accessible so everyone can successfully use them. GitHub is the home for all developers, including those with disabilities. We don’t want to stop at making GitHub accessible; we want to empower other developers to make a similar pattern accessible, which is why we’ll be open sourcing this component!

Process

GitHub is a very large organization with many moving pieces. Making sure that accessibility is considered in every step of the process is important. Our process looked a little something like this:

The first step was that we, the Accessibility Team at GitHub, worked closely with the designers and feature teams to design and build the QueryBuilder component. We wanted to understand the intent of the component and what the user should be able to accomplish. We used this information to help construct the product requirements.

Our designers and accessibility experts worked together on several iterations of what this experience would look like and annotated how it should function. Once everyone agreed on a path forward, it was time to build a proof of concept!

The proof of concept helped to work out some of the trickier parts of the implementation, which we will get to in the following Accessibility Considerations section. An accessibility expert review was conducted at multiple points throughout the process.

The Accessibility Team built the reusable component in collaboration with the Primer Team (GitHub’s Design System), and then collaborated with the GitHub Discussions Team on what it’d take to integrate the component. At this point in time, we have a fully accessible MVP component that can be seen on any GitHub.com Discussions landing page.

Introducing the QueryBuilder component

The main purpose of the QueryBuilder is to allow a user to enter a query that will narrow their results or complete a search. When a user types, a list of suggestions appears based on their input. This is a common pattern on web, which doesn’t sound too complicated, until you start to consider these desired features:

  • The input should contain visual styling that shows a user if they’ve typed valid input.

Text input with an icon of a magnifier at the beginning. The input text of "language:" is a dark gray and the value "C++" is a shade of medium blue with a highlight background of a lighter blue.

  • When a suggestion is selected, it can either take a user somewhere else (“Jump to”) or append the selection to the input (“Autocomplete”).

Two different search inputs with results. The results in the first example have "Autocomplete" appended to the end of the row of each suggestion. The results in the second example have "Jump to" appended to the end of the row of each suggestion.

  • The set of suggestions should change based on the entered input.

Text input example "is:" is giving a different list of results than "language:" did: Action, Discussion, Marketplace, Pull request, Project, Saved, Topic, User, and Wiki.

  • There should be groups of suggestions within the suggestion box.

Search input with results; first group of items is "Recent" with the Recent header on top. The second group is "Pages" with the Pages header on top of the second group. There is a line separator between each group of items.

Okay, now we’re starting to get more complicated. Let’s break these features down from an accessibility perspective.

Accessibility considerations

Note: these considerations are not comprehensive to every accessibility requirement for the new component. We wanted to highlight the trickier-to-solve issues that may not have been addressed before.

Semantics

We talked about this component needing to take a user’s input and provide suggestions that a user can select from in a listbox. We are using the Combobox pattern, which does exactly this.

Styled input

Zoomed in look at the styling between a qualifier, in this case "language:" and the value, "C++". The qualifier has a label of "color: $fg.default" which is a dark gray, and the value has a label of "color: $fg.accent; background: $bg.accent”, which are a lighter and darker shade of blue.

Natively, HTML inputs do not allow specific styling for individual characters, unless you use contenteditable. We didn’t consider this to be an accessible pattern; even basic mark-up can disrupt the expected keyboard cursor movement and contenteditable’s support for ARIA attributes is widely inconsistent. To achieve the desired styling, we have a styled element – a <div aria-hidden="true"> with <span> elements inside—that is behind the real <input> element that a user interacts with. It is perfectly lined up visually so all of the keyboard functionality works as expected, the cursor position is retained, input text is duplicated inside, and we can individually style characters within the input. We also tested this at high Zoom levels to make sure that everything scaled correctly. color: transparent was added to the real input’s text, so sighted users will see the styled text from the <div>.

While the styled input adds some context for sighted users, we also explored whether we could make this apparent for people relying on a screen reader. Our research led us to create a proof of concept with live-region-based announcements as the cursor was moved through the text. However, based on testing, the screen reader feedback proved to be quite overwhelming and occasionally flaky, and it would be a large effort to accurately detect and manage the cursor position and keyboard functionality for all types of assistive technology users. Particularly when internationalization was taken into account, we decided that this would not be overly helpful or provide good return on investment.

Items with different actions

Search results displaying the "Jump to" appended text to the results in the Recent group and "Autocomplete" appended to the results in the Saved searches group; there is a rectangular highlight over the appended words for emphasis.

Typical listbox items in a combobox pattern only have one action–and that is to append the selected option’s value to the input. However, we needed something more. We wanted some selected option values to be appended to the input, but others to take you to a different page, such as search results.

For options that will append their values to the input when selected, there is no additional screen reader feedback since this is the default behavior of a listbox option. These options don’t have any visual indication (color, underline, etc.) that they will do anything other than append the selection to the input.

When an option will take a user to a new location, we’ve added an aria-label to that option explaining the behavior. For example, an option with the title README.md and description primer/react that takes you directly to https://github.com/primer/react/blob/main/README.md will have aria-label=”README.md, primer/react, jump to this file”. This explains the file (README.md), description/location of the file (primer/react), action (jump to), and type (this file). Since this is acting as a link, it will have visual text after the value stating the action. Since options may have two different actions, having a visual indicator is important so that a user knows what will happen when they make a selection.

Group support

A text input and an expanded list of suggestions. The group titles, "Recent" and "Saved searches,” which contain list items related to those groups, are highlighted.

Groups are fully supported in an accessible way. role="group" is not widely supported inside of listbox for all assistive technologies, so our approach conveys the intent of grouped items to each user, but in different ways.

For sighted users, there is a visual header and separator for each group of items. The header is not focusable, and it has role="presentation" so that it’s hidden from screen reader users because this information is presented in a different way to them (which is described later in this blog). The wrapping <ul> and <li> elements are also given role="presentation" since a listbox is traditionally a list of <li> items inside of one parent <ul>.

For screen reader users, the grouped options are denoted by an aria-label with the content of each list item and the addition of the type of list item. This is the same aria-label as described in the previous section about items with different actions. An example aria-label for a list item with the value primer/react that takes you to the Primer React repository when chosen is “primer/react, jump to this repository.” In this example, adding “repository” to the aria-label gives the context that the item is part of the “Repository” group, the same way the visual heading helps sighted users determine the groups. We chose to add the item type at the end of the aria-label so that screen reader users hear the name of the item first and can navigate through the suggestions quicker. Since the aria-label is different from the visible label, it has to contain the visible label’s text at the beginning for voice recognition software users.

Screen reader feedback

By default, there is no indication to a screen reader user how many suggestions are displayed or if the input is successfully cleared via the optional clear button.

To address this, we added an aria-live region that updates the text whenever the suggestions change or the input is cleared. A screen reader will receive feedback when they press the “Clear” button that the input has been cleared, focus is restored to the input, and how many suggestions are currently visible.

While testing the aria-live updates, we noticed something interesting; if the same number of results are displayed as a user continues typing, the aria-live region will not update. For example, if a user types “zzz” and there are 0 results, and then they add an additional “z” to their query (still 0 results), the screen reader will not re-read “0 results” since the aria-live API did not detect a change in the text. To address this, we are adding and removing a &nbsp; character if the previous aria-live message is the same as the new aria-live message. The &nbsp; will cause the aria-live API to detect a change and the screen reader will re-read the text without an audible indication that a space was added.

Recap

In conclusion, this was a tremendous effort with a lot of teams involved. Thank you to the many Hubbers who collaborated on this effort, and to our accessibility friends at Prime Access Consulting (PAC). We are excited for users to get their hands on this new experience and really accelerate their efficiency in complex searches. This component is currently in production in a repository with GitHub Discussions enabled, and it will be rolling out to more parts of the UI. Stay tuned for updates about the progress of the component being open sourced.

What’s next

We will integrate this component into additional parts of GitHub’s UI, such as the new global search experience so all users can benefit from this accessible, advanced searching capability. We will continue to add the component to other areas of the GitHub UI and address any bugs or feedback we receive.

As mentioned in the beginning of this post, it will be open sourced in Primer ViewComponents and Primer React along with clear guidelines on how to use this component. The base of the component is a Web Component which allows us to share the functionality between ViewComponents and React. This will allow developers to easily create an advanced, accessible, custom search component without spending time researching how to make this pattern accessible or functional, since we’ve already done that work! It can work with any source of data as long as it’s in the expected format.

Many teams throughout GitHub are constantly working on accessibility improvements to GitHub.com. For more on our vision for accessibility at GitHub, visit accessibility.github.com.

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards

Post Syndicated from Emily Flannery original https://blog.cloudflare.com/project-a11y/

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards

At Cloudflare, we believe the Internet should be accessible to everyone. And today, we’re happy to announce a more inclusive Cloudflare dashboard experience for our users with disabilities. Recent improvements mean our dashboard now adheres to industry accessibility standards, including Web Content Accessibility Guidelines (WCAG) 2.1 AA and Section 508 of the Rehabilitation Act.

Over the past several months, the Cloudflare team and our partners have been hard at work to make the Cloudflare dashboard1 as accessible as possible for every single one of our current and potential customers. This means incorporating accessibility features that comply with the latest Web Content Accessibility Guidelines (WCAG) and Section 508 of the US’s federal Rehabilitation Act. We are invested in working to meet or exceed these standards; to demonstrate that commitment and share openly about the state of accessibility on the Cloudflare dashboard, we have completed the Voluntary Product Accessibility Template (VPAT), a document used to evaluate our level of conformance today.

Conformance with a technical and legal spec is a bit abstract–but for us, accessibility simply means that as many people as possible can be successful users of the Cloudflare dashboard. This is important because each day, more and more individuals and businesses rely upon Cloudflare to administer and protect their websites.

For individuals with disabilities who work on technology, we believe that an accessible Cloudflare dashboard could mean improved economic and technical opportunities, safer websites, and equal access to tools that are shaping how we work and build on the Internet.

For designers and developers at Cloudflare, our accessibility remediation project has resulted in an overhaul of our component library. Our newly WCAG-compliant components expedite and simplify our work building accessible products. They make it possible for us to deliver on our commitment to an accessible dashboard going forward.

Our Journey to an Accessible Cloudflare Dashboard

In 2021, we initiated an audit with third party experts to identify accessibility challenges in the Cloudflare dashboard. This audit came back with a daunting 213-page document—a very, very long list of compliance gaps.

We learned from the audit that there were many users we had unintentionally failed to design and build for in Cloudflare dashboard user interfaces. Most especially, we had not done well accommodating keyboard users and screen reader users, who often rely upon these technologies because of a physical impairment. Those impairments include low vision or blindness, motor disabilities (examples include tremors and repetitive strain injury), or cognitive disabilities (examples include dyslexia and dyscalculia).

As a product and engineering organization, we had spent more than a decade in cycles of rapid growth and product development. While we’re proud of what we have built, the audit made clear to us that there was a great need to address the design and technical debt we had accrued along the way.

One year, four hundred Jira tickets, and over 25 new, accessible web components later, we’re ready to celebrate our progress with you. Major categories of work included:

  1. Forms: We re-wrote our internal form components with accessibility and developer experience top of mind. We improved form validation and error handling, labels, required field annotations, and made use of persistent input descriptions instead of placeholders. Then, we deployed those component upgrades across the dashboard.
  2. Data visualizations: After conducting a rigorous re-evaluation of their design, we re-engineered charts and graphs to be accessible to keyboard and screen reader users. See below for a brief case study.
  3. Heading tags: We corrected page structure throughout the dashboard by replacing all our heading tags (<h1>, <h2>, etc.) with a technique we borrowed from Heydon Pickering. This technique is an approach to heading level management that uses React Context and basic arithmetic.
  4. SVGs: We reworked how we create SVGs (Scalable Vector Graphics), so that they are labeled properly and only exposed to assistive technology when useful.
  5. Node modules: We jumped several major versions of old, inaccessible node modules that our UI components depend upon (and we broke many things along the way).
  6. Color: We overhauled our use of color, and contributed a new volume of accessible sequential colors to our design system.
  7. Bugs: We squashed a lot of bugs that had made their way into the dashboard over the years. The most common type of bug we encountered related to incorrect or unsemantic use of HTML elements—for example, using a <div> where we should have used a <td> (table data) or <tr> (table row) element within a table.

Case Study: Accessibility Work On Cloudflare Dashboard Data & Analytics

The Cloudflare dashboard is replete with analytics and data visualizations designed to offer deep insight into users’ websites’ performance, traffic, security, and more. Making those data visualizations accessible proved to be among the most complex and interdisciplinary issues we faced in the remediation work.

An example of a problem we needed to solve related to WCAG success criterion 1.4.1, which pertains to the use of color. 1.4.1 specifies that color cannot be the only means by which to convey information, such as the differentiation between two items compared in a chart or graph.

Our charts were clearly nonconforming with this standard, using color alone to represent different data being compared. For example, a typical graph might have used the color blue to show the number of requests to a website that were 200 OK, and the color orange to show 403 Forbidden, but failed to offer users another way to discern between the two status codes.

Our UI team went to work on the problem, and chose to focus our effort first on the Cloudflare dashboard time series graphs.

Interestingly, we found that design patterns recommended even by accessibility experts created wholly unusable visualizations when placed into the context of real world data. Examples of such recommended patterns include using different line weights, patterns (dashed, dotted or other line styles), and terminal glyphs (symbols set at the beginning and end of the lines) to differentiate items being compared.

We tried, and failed, to apply a number of these patterns; you can see the evolution of this work on our time series graph component in the three different images below.

v.1

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards
Here is an early attempt at using both terminal glyphs and patterns to differentiate data in a time series graph. You can see that the terminal glyphs pile up and become indistinguishable; the differences among the line patterns are very hard to discern. This code never made it into production.

v.2

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards
In this version, we eliminated terminal glyphs but kept line patterns. Additionally, we faded the unfocused items in the graph to help bring highlighted data to the forefront. This latter technique made it into our final solution.

v.3

Project A11Y: how we upgraded Cloudflare’s dashboard to adhere to industry accessibility standards
Here we eliminated patterns altogether, simplified the user interface to only use the fading technique on unfocused items, and put our new, sequentially accessible colors to use. Finally, a visual design solution approved by accessibility and data visualization experts, as well as our design and engineering teams.

After arriving at our design solution, we had some engineering work to do.

In order to meet WCAG success criterion 2.1.1, we rewrote our time series graphs to be fully keyboard accessible by adding focus handling to every data point, and enabling the traversal of data using arrow keys.

Navigating time series data points by keyboard on the Cloudflare dashboard.

We did some fine-tuning, specifically to support screen readers: we eliminated auditory “chartjunk” (unnecessary clutter or information in a chart or graph) and cleaned up decontextualized data (a scenario in which numbers are exposed to and read by a screen reader, but contextualizing information, like x- and y-axis labels, is not).

And lastly, to meet WCAG 1.1.1, we engineered new UI component wrappers to make chart and graph data downloadable in CSV format. We deployed this part of the solution across all charts and graphs, not just the time series charts like those shown above. No matter how you browse and interact with the web, we hope you’ll notice this functionality around the Cloudflare dashboard and find value in it.

Making all of this data available to low vision, keyboard, and assistive technology users was an interesting challenge for us, and a true team effort. It necessitated a separate data visualization report conducted by another, more specialized team of third party experts, deep collaboration between engineering and design, and many weeks of development.

Applying this thorough treatment to all data visualizations on the Cloudflare dashboard is our goal, but still work in progress. Please stay tuned for more accessible updates to our chart and graph components.

Conclusion

There’s a lot of nuance to accessibility work, and we were novices at the beginning: researching and learning as we were doing. We also broke a lot of things in the process, which (as any engineering team knows!) can be stressful.

Overall, our team’s biggest challenge was figuring out how to complete a high volume of cross-functional work in the shortest time possible, while also setting a foundation for these improvements to persist over time.

As a frontend engineering and design team, we are very grateful for having had the opportunity to focus on this problem space and to learn from truly world-class accessibility experts along the way.

Accessibility matters to us, and we know it does to you. We’re proud of our progress, and there’s always more to do to make Cloudflare more usable for all of our customers. This is a critical piece of our foundation at Cloudflare, where we are building the most secure, performant and reliable solutions for the Internet. Stay tuned for what’s next!

Not using Cloudflare yet? Get started today and join us on our mission to build a better Internet.

1All references to “dashboard” in this post are specific to the primary user authenticated Cloudflare web platform. This does not include Cloudflare’s product-specific dashboards, marketing, support, educational materials, or third party integrations.

More devices, fewer CAPTCHAs, happier users

Post Syndicated from Wesley Evans original https://blog.cloudflare.com/cap-expands-support/

More devices, fewer CAPTCHAs, happier users

More devices, fewer CAPTCHAs, happier users

Earlier this year we announced that we are committed to making online human verification easier for more users, all around the globe. We want to end the endless loops of selecting buses, traffic lights, and convoluted word diagrams. Not just because humanity wastes 500 years per day on solving other people’s machine learning problems, but because we are dedicated to making an Internet that is fast, transparent, and private for everyone. CAPTCHAs are not very human-friendly, being hard to solve for even the most dedicated Internet users. They are extremely difficult to solve for people who don’t speak certain languages, and people who are on mobile devices (which is most users!).

Today, we are taking another step in helping to reduce the Internet’s reliance on CAPTCHAs to prove that you are not a robot. We are expanding the reach of our Cryptographic Attestation of Personhood experiment by adding support for a much wider range of devices. This includes biometric authenticators — like Apple’s Face ID, Microsoft Hello, and Android Biometric Authentication. This will let you solve challenges in under five seconds with just a touch of your finger or a view of your face — without sending this private biometric data to anyone.

You can try it out on our demo site cloudflarechallenge.com and let us know your feedback.

In addition to support for hardware biometric authenticators, we are also announcing support for many more hardware tokens today in the Cryptographic Attestation of Personhood experiment. We support all USB and NFC keys that are both certified by the FIDO alliance and have no known security issues according to the FIDO Alliance Metadata service (MDS 3.0).

Privacy First

Privacy is at the center of Cryptographic Attestation of Personhood. Information about your biometric data is never shared with, transmitted to, or processed by Cloudflare. We simply never see it, at all. All of your sensitive biometric data is processed on your device. While each operating system manufacturer has a slightly different process, they all rely on the idea of a Trusted Execution Environment (TEE) or Trusted Platform Module (TPM). TEEs and TPMs allow only your device to store and use your encrypted biometric information. Any apps or software running on the device never have access to your data, and can’t transmit it back to their systems. If you are interested in digging deeper into how each major operating system implements their biometric security, read the articles we have linked below:

Apple (Face ID and Touch ID)

Face ID and Touch ID Privacy
Secure Enclave Overview

Microsoft (Windows Hello)

Windows Hello Overview
Windows Hello Technical Deep Dive

Google (Android Biometric Authentication)

Biometric Authentication
Measuring Biometric Unlock Security

Our commitment to privacy doesn’t just end at the device. The WebAuthn API also prevents the transmission of biometric information. If a user interacts with a biometric key (like Apple TouchID or Windows Hello), no third party — such as Cloudflare — can receive any of that biometric data: it remains on your device and is never transmitted by your browser. To get an even deeper understanding of how the Cryptographic Attestation of Personhood protects your private information, we encourage you to read our initial announcement blog post.

Making a Great Privacy Story Even Better

While building out this technology, we have always been committed to providing the best possible privacy guarantees. The existing assurances are already quite strong: as described in our previous post, when using CAP, you may disclose a small amount of information about your authentication hardware — at most, its make and model. By design, this information is not unique to you: the underlying standard requires that this be indistinguishable from thousands of others, which hides you in a crowd of identical hardware.

Even though this is a great start, we wanted to see if we could push things even farther. Could we learn just the one fact that we need — that you have a valid security key — without learning anything else?

We are excited to announce that we have made great strides on answering that question by using a form of the next generation of cryptography called Zero Knowledge Proofs (ZKP). ZKP prevents us from discovering anything from you, other than the fact that you have a device that can generate an approved certificate that proves that you are human.

If you are interested in learning more about Zero Knowledge Proofs, we highly recommend reading about it here.

Driven by Speed, Ease of Use, and Bot Defense

At the start of this project we set out three goals:

  1. How can we dramatically improve the user experience of proving that you are a human?
  2. How can we make sure that any solution that we develop centers around ease of use, and increases global accessibility on the Internet?
  3. How do we make a solution that does not harm our existing bot management system?

Before we deployed this new evolution of our CAPTCHA solution, we did a proof of concept test with some real users, to confirm whether this approach was worth pursuing (just because something sounds great in theory doesn’t mean it will work out in practice!). Our testing group tried our Cryptographic Attestation of Personhood solution using Face ID and told us what they thought. We learned that solving times with Face ID and Touch ID were significantly faster than selecting pictures, with almost no errors. People vastly preferred this alternative, and provided suggestions for improvements in the user experience that we incorporated into our deployment.

This was even more evident in our production usage data. While we did not enable attestation with biometrics providers during our first phase of the CAP roll out, we did record when people attempted to use a biometric authentication service. The highest recorded attempt solve rate besides YubiKeys was Face ID on iOS, and Android Biometric Authentication. We are excited to offer those mobile users their first choice of challenge for proving their humanity.

One of the things we heard about in testing was — not surprisingly — concerns around privacy. As we explained in our initial launch, the WebAuthn technology underpinning our solution provides a high level of privacy protection. Cloudflare is able to view an identifier shared by thousands of similar devices, which provides general make and model information. This cannot be used to uniquely identify or track you — and that’s exactly how we like it.

Now that we have opened up our solution to more device types, you’re able to use biometric readers as well. Rest assured that the same privacy protections apply — we never see your biometric data: that remains on your device. Once your device confirms a match, it sends only a basic attestation message, just as it would for any security key. In effect, your device sends a message proving that “yes, someone correctly entered a fingerprint on this trustworthy device”, and never sends the fingerprint itself.

We have also been reviewing feedback from people who have been testing out CAP on either our demo site or through routine browsing. We appreciate the helpful comments you’ve been sending, and we’d love to hear more, so we can continue to make improvements. We’ve set up a survey at our demo site. Your input is key to ensuring that we get usability right, so please let us know what you think.