Политическите убийства не би следвало да се разглеждат като различни от останалите тежки престъпления, тъй като правото на живот, както казва Джон Лок, стои над всички останали естествени права. Но когато подобно престъпление бъде извършено в страна, за която се смята, че притежава най-развитата демокрация, е редно да се запитаме дали естествените права и производните от тях свободи не се използват от престъпниците, за да рушат сигурността в обществото.
От друга страна, САЩ имат богата история на политически убийства, като сред тях се открояват атентатите срещу четирима американски президенти: Ейбрахам Линкълн, Джеймс Гарфийлд, Джон Маккинли и Джон Кенеди. Не по-малко потресаващи са посегателствата срещу живота на сенаторите Робърт Кенеди и Хюи Лонг. Впрочем тъкмо от консервативния месиански проект на Лонг Доналд Тръмп заимства идеите си.
Като изключим ранните покушения в американската история, които обикновено се свързват с наследените от Британия „джентълменски“ привички за разчистване на сметките, и актовете на отмъщение, предприети от страна на индианските племена, всички политически убийства в САЩ си приличат по две неща. Първо, жертвите са политици, чиито идеи и политически проекти разделят американското общество така, както политическият плурализъм на демокрациите не може да го направи. Второ, извършителят на убийството умело използва свободите, които предоставя американската демокрация, за да планира и приведе в действие стратегията си.
В този анализ ще се опитаме да отговорим на въпроса къде лежи вината за политическите убийства в САЩ и защо случилото се с Чарли Кърк не прави изключение от печалната традиция в американската история.
Между личната мотивация и дебата за Втората поправка
Когато човек е мотивиран да извърши убийство – освен ако не става въпрос за лице с психични отклонения, – той възприема отнемането на човешкия живот като свое право да упражнява власт върху живота на останалите хора. Това е основният мотив, който стои зад желанието на повечето престъпници да убиват. Затова от хората, вярващи в конспиративни теории, излизат „най-добрите“ убийци.
Вярата в абстрактни идеи, лишени от всякакви доказателства, може да радикализира дори и най-образования човек, превръщайки го в престъпник.
Палачите на политическия елит в САЩ обикновено са мотивирани или от крайна омраза към идеите на въпросния политик, или става въпрос за строго специфични причини, които американското правителство е предпочело да засекрети. Може би някой ден ще разберем кой стои зад убийството на Джон Кенеди, но дотогава е добре да се въздържаме от едностранни тълкувания, които биха могли да превърнат дори и най-жестоките убийци в мъченици.
Любопитното в мотивацията на извършителите на такива престъпления е, че те обикновено използват американската демокрация като трамплин да убиват – да закупиш оръжие в САЩ е изключително лесно и тази практика не се е променяла още от създаването на държавата. Втората поправка в Конституцията на САЩ защитава правото на американските граждани да притежават и свободно да носят оръжие, а конституционалистите легитимират това право с презумпцията, че благодарение на него американците са формирали своя отбранителен капацитет в годините, когато не са имали армия. Привържениците на Втората поправка ще ви кажат, че Гражданската война, независимостта от Британия и овладяването на Дивия запад са резултат от тази свобода и че без нея Америка днес нямаше да съществува.
Критиците, от друга страна, постоянно обръщат внимание на факта, че историческите реалности, в които живее американското общество, вече са други, и затова Втората поправка по-скоро вреди и радикализира определени групи от обществото, отколкото гарантира неговата сигурност. Но да отмениш Втората поправка не е лесно начинание, тъй като тя е част от Закона за правата – първите десет поправки от американската Конституция, които имат свещен характер за конституционната традиция на страната, както и американският федерализъм. Нещо повече, последните решения на Върховния съд от 2010 г. (делото McDonald v. City of Chicago) и 2022 г. (New York State Rifle & Pistol Association, Inc. v. Bruen) по-скоро защитават и разширяват обхвата на Втората поправка, отколкото го ограничават.
Краят на мандата на Джо Байдън беляза първата решителна крачка в дебата за Втората поправка, като през 2024 г. с делото United States v. Rahimi Върховният съд даде на федералното правителство правомощието да разоръжава лица, които представляват опасност за обществената сигурност, и отмени абсолютния характер на поправката.
Този на пръв поглед разумен ход на най-висшата съдебна инстанция в САЩ създаде повече проблеми, отколкото разреши, тъй като немалко щати, в които републиканците традиционно доминират в общественото мнение, бойкотираха решението, макар да бяха длъжни да се съобразят с него.
Противопоставянето беше пряк резултат от призивите на крайнолевите движения в САЩ, като Black Lives Matters(BLM), полицията да бъде лишена от бюджет и разпусната като неефективен правоприлагащ орган, а гражданите да вземат нещата в свои ръце – идеи, придобили особена популярност в американското общество след убийството на Джордж Флойд. Така Америка влезе в една спирала на насилието, в която личната мотивация да извършиш престъпление на практика беше легитимирана от правата и свободите, дадени на гражданите от законите на страната. Това е и основната причина, поради която американското общество стана жертва на сериозно разделение – то отслаби САЩ и диктатурите по света се възползваха от него.
Казусът „Чарли Кърк“ и неизбежната поляризация
Преди всичко е редно да отбележим, че убийството на Чарли Кърк е проява на тероризъм, тъй като следва точно параметрите на това определение. Подобно на повечето консервативни лобисти в САЩ, гласът на Кърк се чуваше ясно и директно. До този момент няма никаква информация да е бил разследван за престъпление или да е извършвал такова. Кърк не е и със статус на военен служител или представител на службите. Междувременно се появи слух, че висши военни обмислят кампания за набиране на нови попълнения за армията със слоган в подкрепа на опазването на завета на Чарли Кърк. Пентагонът официално отрече тази информация.
В духа на американската правна традиция това позиционира Кърк като цивилен, който е станал жертва на предварително организирано убийство. Точно тук трябва да бъдем особено внимателни, тъй като цивилният статус на лобистите в САЩ ги поставя редом до всички останали граждани, независимо от позицията, която заемат в обществото. Консерватор, поддръжник на Втората поправка, привърженик на Доналд Тръмп – всичко това не е причина Чарли Кърк да умре. Още по-малко пък е причината определени групи в американското общество да празнуват неговата смърт, както САЩ празнуваха, след като ликвидираха терориста Осама бин Ладен.
Вторият основен момент в този казус е, че извършителят Тайлър Джеймс Робинсън може да послужи като перфектния профил за лице, извършващо политически убийства. Пътят към неговата радикализация е класически и отговаря на методологията, която ФБР използва при разглеждането на случаите си. С една малка разлика – радикализацията на заподозрения е настъпила в мирно време и на свобода, с неограничен достъп до интернет, а не в затвора.
Нужно е да обърнем внимание на този важен детайл, тъй като от 11 септември насам поколения изследователи на тероризма ни убеждаваха, че от затворите излизат най-добрите терористи, а образованието и програмите за дерадикализация са най-сигурният начин да се сложи край на политически мотивираното насилие. Хипотезата е все още актуална и приложима за терористите, които взривяваха сгради и убиваха цивилни в името на религиозните си убеждения, но не може да ни даде обяснение за другата форма на тероризъм, която набира популярност в САЩ и много скоро ще се появи и в Европа. Част от това обяснение може би се крие в т.нар. онлайн радикализация, за каквато имаше информация и по линия на Тайлър Робинсън – атентатора на Кърк.
Убийството на Чарли Кърк не трябва да се обгражда в конспиративен ореол. Не съществуват никакви доказателства, че Кърк е сътрудничил на американските или на чужди разузнавателна служби. Тази фалшива новина обиколи някои ирански медии, които публикуваха подвеждаща информация от недостоверен източник, че израелските разузнавателни служби носят отговорност за случилото се. По същото време, когато Иран разпространява „информацията“ кой е организирал убийството на Кърк, редица руски и китайски интернет тролове публикуват още конспиративни твърдения, че оръжието, с което е извършено престъплението, е използвано от Мосад. Всичко това на фона на информацията от ФБР, че произходът на пушката, с която беше застрелян Чарли Кърк, е толкова стар, че не може да бъде проследена в архивите. Е, всеки оръжеен търговец в САЩ ще ви каже, че стари оръжия може да купите единствено и само от т.нар. американски оръжейни брокери, които не пазят архиви, тъй като по-голямата част от оръжията са внесени незаконно в страната.
Кой е убиецът и коя е жертвата?
Казаното дотук означава три неща. Първо, че убийството на Чарли Кърк е придружено с огромна вълна от дезинформация. Нейната таргет група са американските консерватори и особено християнските деноминации, които са известни с традиционната си и последователна подкрепа за Израел. Тези слухове продължават да се разпространяват, разбира се, с много по-малък интензитет. Но ако общественото мнение продължи да попива подобни тези, е възможно Америка да осъмне с антисемитски лозунги в близко бъдеще. Всичко зависи от медиите в САЩ и от начина, по който те ще се преборят с наративите, идващи от Иран, Русия и Китай. Фактът, че стратегическите съперници на САЩ насочиха своята реторика срещу Израел, означава, че целят разтрогване на единството между Вашингтон и Тел Авив – цел, която вече беше постигната в Европа. Още по-лошото е, че атентаторите от крайнодесния спектър постигат същия ефект с лозунгите си в подкрепа на Израел и на традиционните ценности в САЩ. Това също генерира расова и етническа омраза, която поляризира още повече и без това разделеното американско общество.
Второ, Чарли Кърк няма да е последният политик, срещу когото ще бъде направен опит за убийство, а подобни актове на насилие ще се използват от съперниците на САЩ по света, за да дестабилизират политическия живот в страната. И тук е важно да отбележим още нещо: еднакво уязвими са както консервативните, така и либералните политици. Всички помним вероломното нападение от това лято срещу Мелиса Хортман – бившата председателка на Камарата на представителите в щата Минесота, при което тя и съпругът ѝ бяха убити. По-рано през деня същият извършител, преоблечен като полицай, отива до дома на сенатора демократ Джон Хофман, прострелва го 9 пъти, съпругата му Ивет – 8 пъти и прави опит да стреля и по дъщеря им. Семейство Хофман оцелява като по чудо. Извършителят на покушенията над двете семейства е частният охранител Ванс Болтър, който е американски гражданин с ултраконсервативни убеждения.
Такива актове на политическо насилие по нищо не се различават от случилото се с Чарли Кърк и дори е изненадващо, че за тях се вдигна много по-малко шум.
Политическите убийства доказват, че общественото мнение в САЩ е толкова разделено, че самото общество започва да се разпада на различни субкултури, някои от които се опитват да прилагат самоосъзнати форми на политическа власт със силата на оръжието, или казано по-просто – да раздават улично правосъдие. А това сериозно подронва устоите на американската демокрация.
Класическият либерализъм на Джон Лок ни учи, че Бог е дал на хората естествени права, които никой не може да им отнеме. Но по време на втория мандат на Обама демократите не успяха да овладеят разрушителните инстинкти, които дремеха в по-младото поколение избиратели, и така се появи нова вълна на ляво мислене, систематично подкрепяна и финансирана от Китай.
Отговорът дойде от крайнодесните политически фракции, чиито конспиративни идеи черпеха вдъхновение и парична подкрепа от идеолозите на руското неоевразийство в лицето на Александър Дугин и неговите последователи. Така Москва и Пекин получиха достъп до политическия и обществен дебат в Америка, както и до възможността да го манипулират. В тези условия много западни политици решиха удобно да си затворят очите, заблуждавайки се, че държат нещата под контрол и че новите им лобисти няма да се изплъзнат от ръцете им.
Логичният извод е, че зад убийството на поредната американска политическа фигура стоят фактори и движещи сили, които далеч надхвърлят мотивацията на един гражданин да вземе оръжието и да убие човек. Разделението в американското общество е част от жизнения цикъл на историята, в който тоталитарните режими и автокрациите се опитват да унищожат демокрациите и свободомислещите хора, като манипулират техните идеи и ги превръщат в патологии. А разликата между свободата на идеите и патологиите е много проста: конфликтите, които произтичат от различията ни, са норма; насилието, което произтича от манипулираните различия, е патология.
Американската демокрация обаче не може да бъде унищожена с помощта на ядрена бомба, флот или оръжия. Просто защото на този етап САЩ все още са най-силната страна в света. Ликвидирането на свободата в нея минава през разделението на хората, подронването на доверието в американската демокрация и унищожаването на системата от съюзи, които Вашингтон изгражда след края на Втората световна война. Ако този план успее, демокрацията рухне и хората започнат да раздават правосъдие по улиците, едва ли някой ще помни как и защо Чарли Кърк е загубил живота си. И нека не се успокояваме, че тези процеси ще подминат България. Страната ни е толкова интегрирана в глобализацията, че събитията ще ни застигнат много скоро, но ще бъдат строго пречупени през призмата на националната ни специфика. Остава въпросът дали сме толкова разделени и объркани, че да допуснем някой да раздава улично правосъдие. Можем само да се надяваме, че не.
High availability on a platform like Zabbix is a hard requirement for many users. With native high availability on the Zabbix servers, proxies, and at the frontend through various solutions for web servers, all that’s left is at the database layer. Any downtime in your MariaDB database would disrupt your monitoring availability, at the least on the frontend side of things in case of proxy buffering. Let’s have a look at the easiest way to create a high availability (HA) architecture for Zabbix using MariaDB with built-in Galera clustering – by removing single points of failure from your database and finalizing the HA puzzle for Zabbix.
Architecture overview
Let’s start of with the MariaDB + Galera number one design requirement. For a proper quorum to be made, 3 nodes should be used in the cluster. With only two nodes in a Galera cluster, quorum rules become a bit of a headache, as Galera uses a majority vote (more than half the nodes) to decide if the cluster can still accept writes. In a two-node setup, all is good when the database is online. But when we lose one node, quorum is lost and that node needs to rejoin.
This makes a two-node setup fragile but not impossible, and it does work with Zabbix since we do only have one Zabbix server active at the time. In a split-brain scenario where both nodes either think they are the last to leave, you might have to decide which node you think has your up-to-date data. We will detail both scenario’s, but the principle remains the same. We will use MariaDB as our database and Galera will be used to create a primary/primary cluster. In such a cluster, all nodes in the cluster are writeable, which is great for the Zabbix native HA.
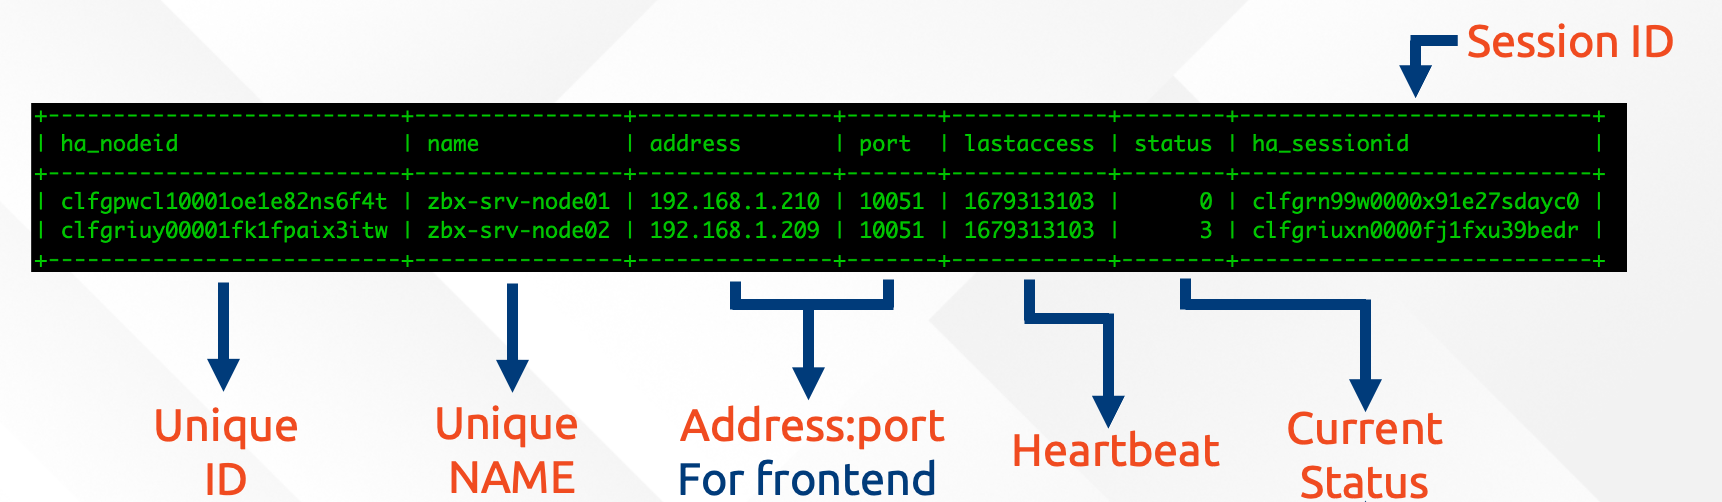
When we look in the Zabbix database, we can see that Zabbix keeps all of it’s Zabbix server HA information and states in the database.
This means that whatever one Zabbix server node writes into the database will also be replicated to all other nodes in the MariaDBGalera cluster.
The design
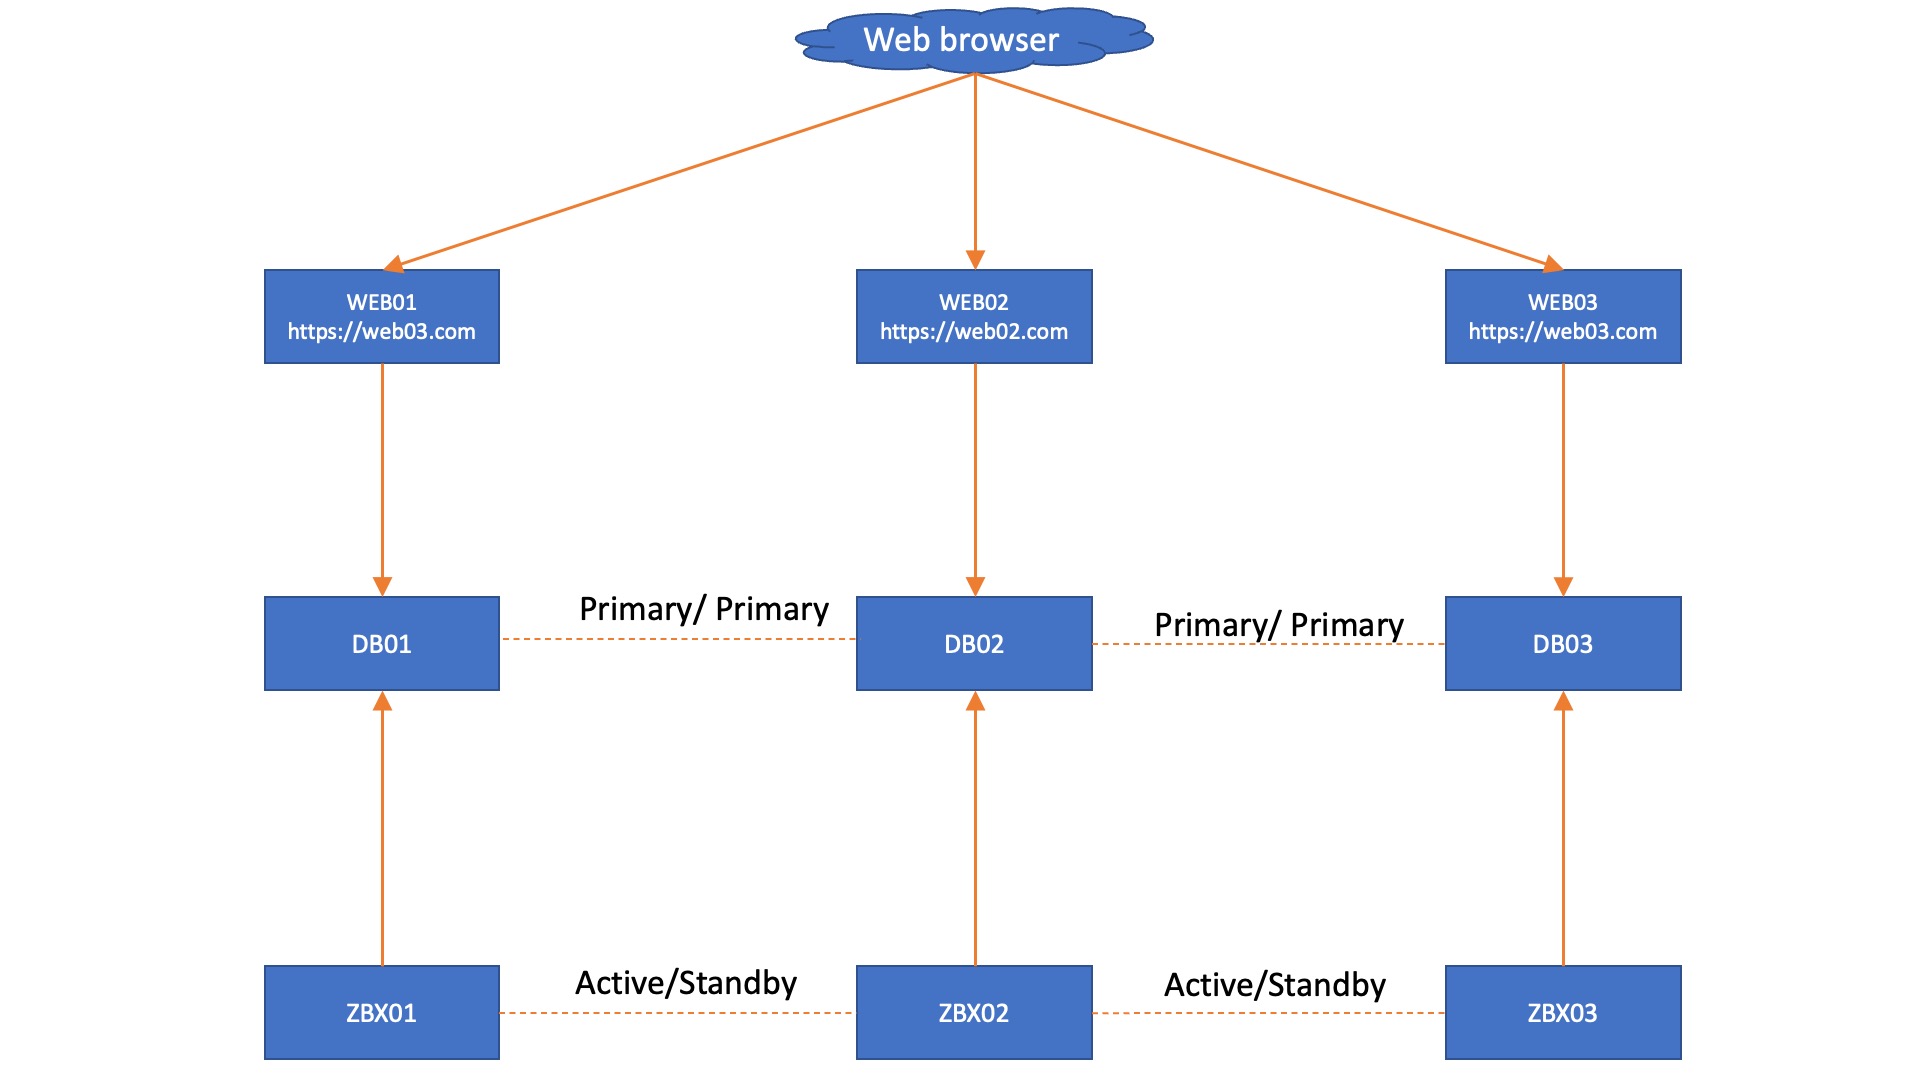
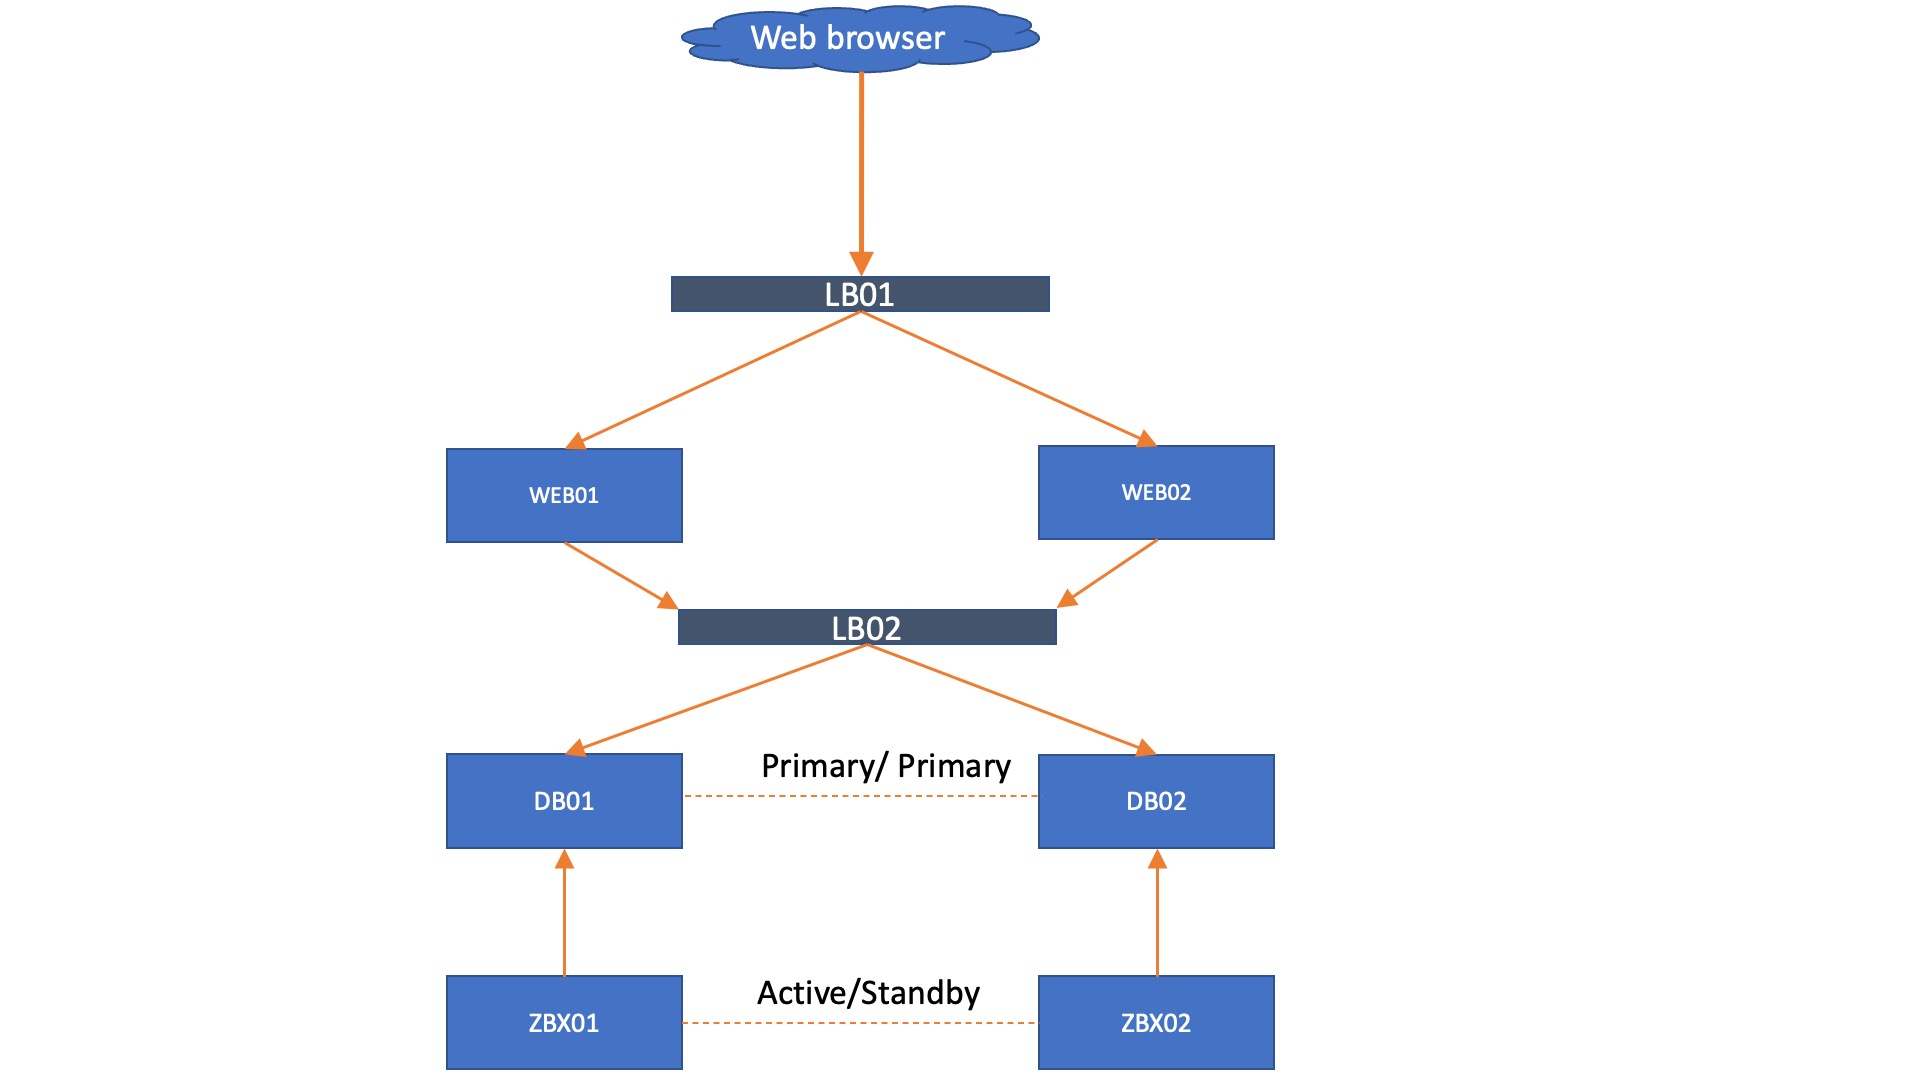
Knowing what we know now, we can create a very simple design for a solid Zabbix HA setup with Mariadb + Galera. When we have a single Zabbix frontend and we keep to the MariaDB + Galera requirement of having 3 database nodes, we get a fairly simple setup, as seen below.
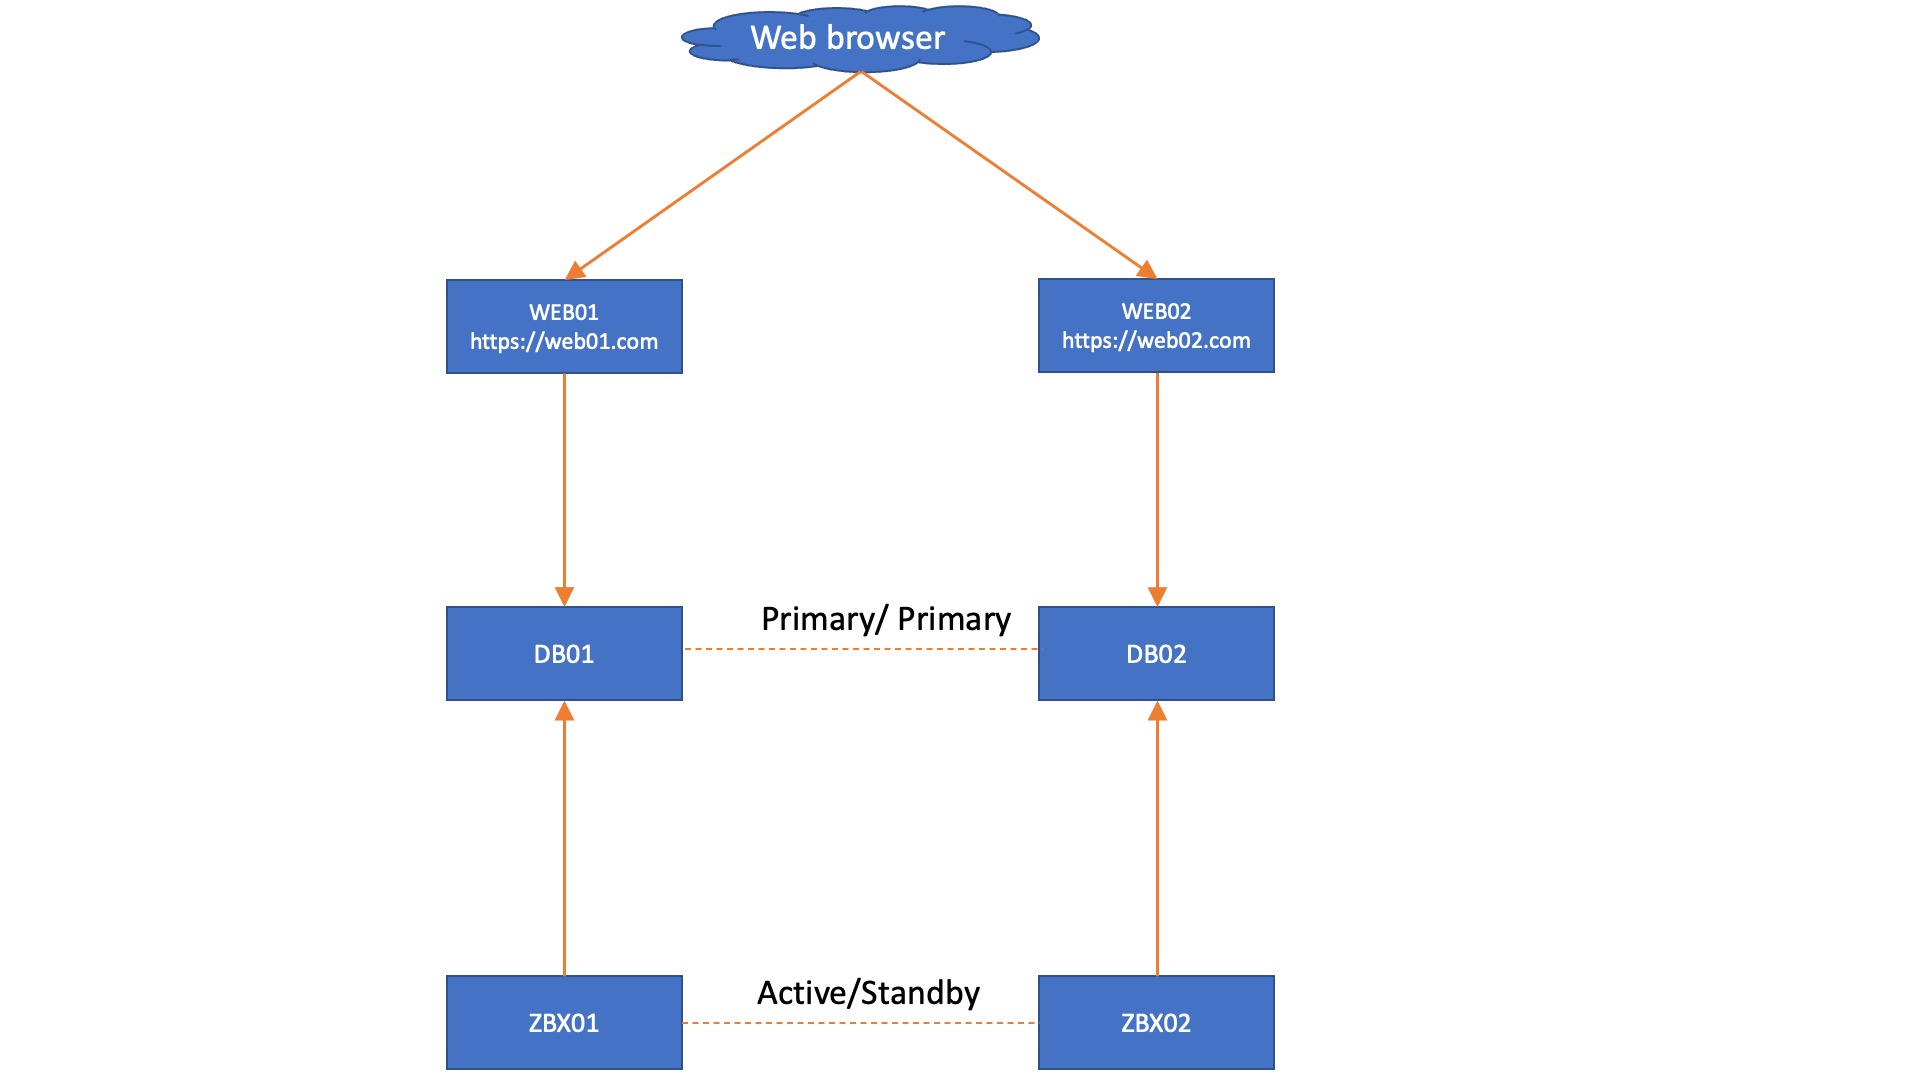
In this setup, each Zabbix server connects to its own Database node and we don’t need added complexity by using load balancers. However, we do get an automatic failover from the Zabbix servers, as they know exactly which node is active through the database. However, in this situation we are still left with 3 frontends that do not have automatic failover, simply because we do not have database aware Apache or NGINX. This also works in a two database setup, with the side note that you might have quorum issues to manually resolve after an outage:
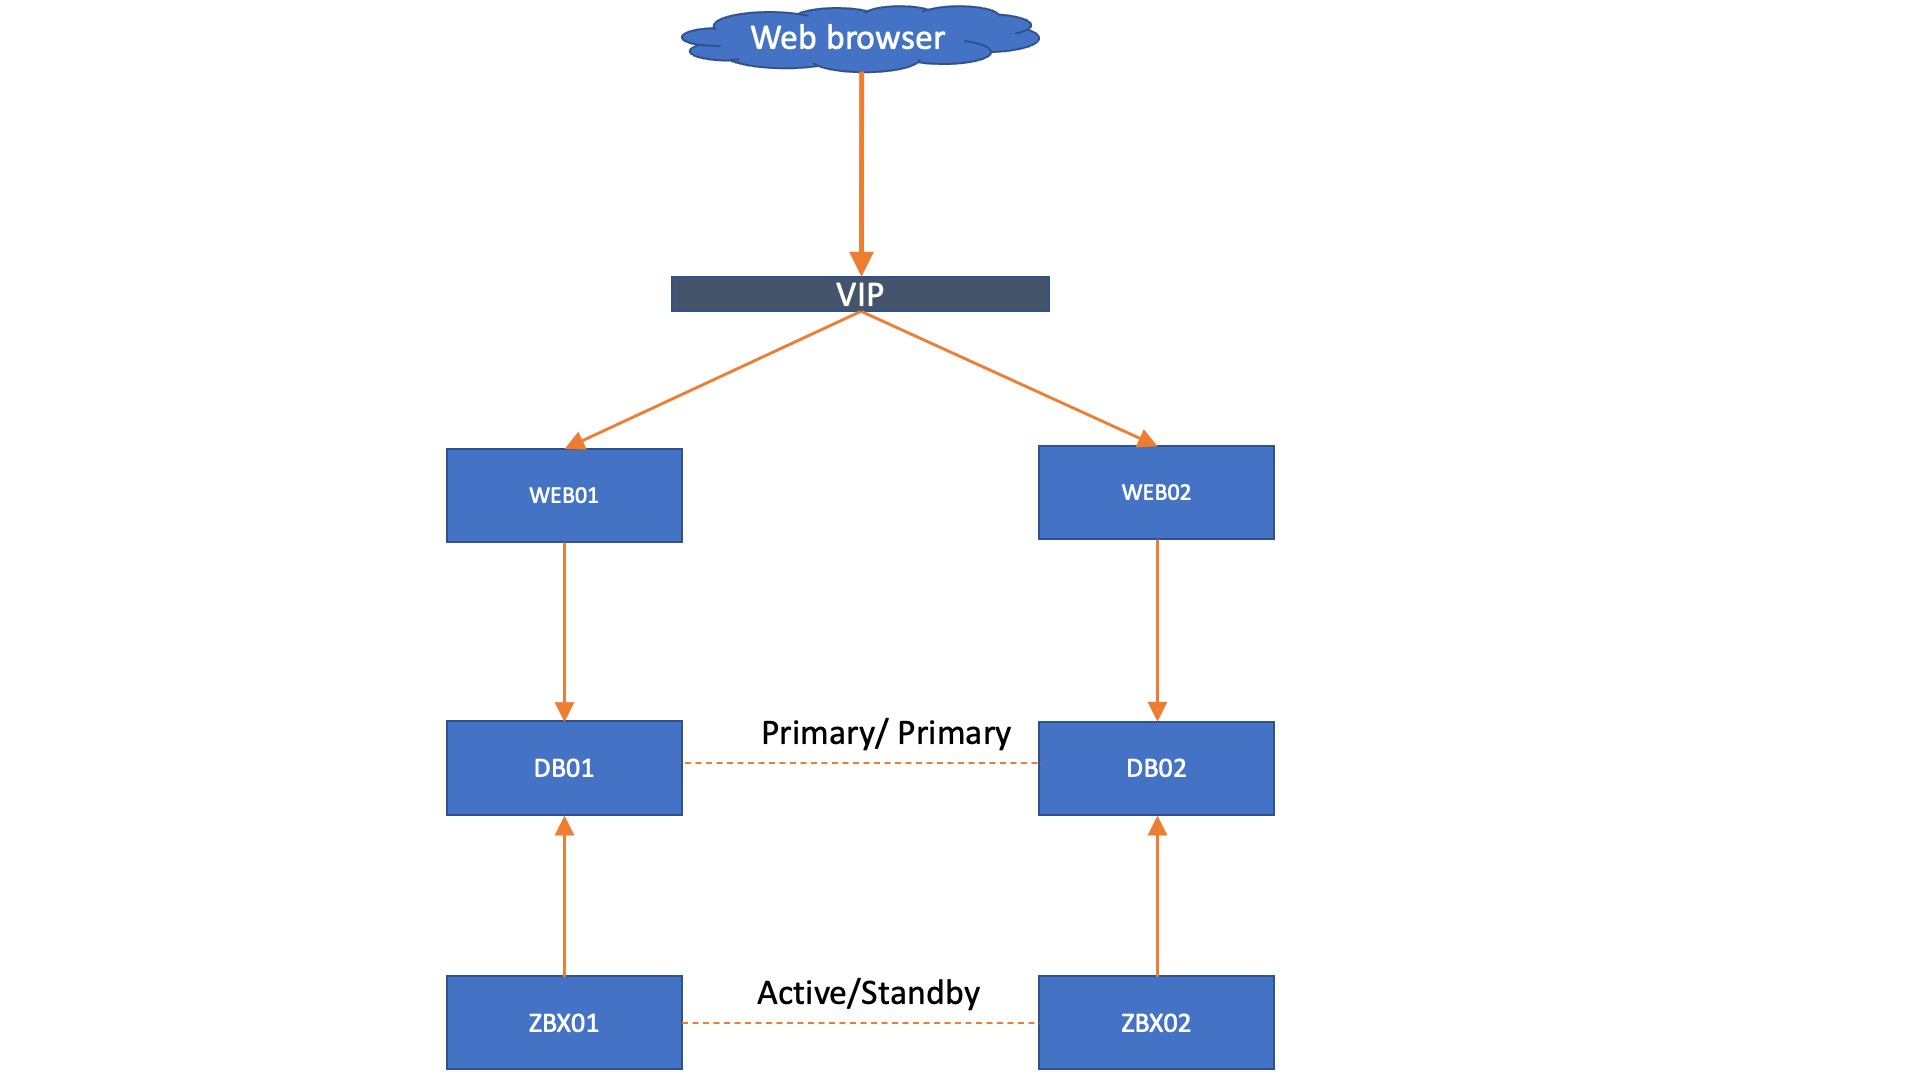
Adding onto this setup, we could install a VIP, load balancer, or something like HA proxy in front of the frontend to make a failover happen there as well. Keep in mind though, the failover needs to happen based on whether or not the webfrontend can reach a writeable database.
Optional Arbitrator
If you are set on running only 2 database nodes (your wallet is thankful), but still worried about quorums, we can bring in the ARBITRATOR.
If there are only 2 Database nodes in your Galera cluster, not to worry! It’s definitely possible even while maintaining a good quorum resolution in case of outages.
What about load balancing?
Lastly, it is also possible to add load balancing to the mix. Let’s say, for example, you cannot add a VIP to your environment but still need your WEB servers to failover. A load balancer can provide the solution here.
We still prefer to run the Zabbix servers with a direct database connection, but even there a load balancer could be added if you wish. However, please keep in mind that the more load balancers you add, the more complex troubleshooting might become. The whole idea about the setup without load balancers is to have a solid Zabbix setup that is easy to maintain, while providing high availability.
Conclusion
In the end, even with a minimal setup of 2 DB nodes, 2 Zabbix servers, and 2 WEB frontends, we can make a high availability setup. As we’ve shown with Galera, this setup becomes highly flexible, allowing us to run without automatic WEB failover all the way up to including complicated load balancers.
High availability doesn’t have to be overly complicated in a setup like this – it really is all about how far you want to push things. Besides that, in this setup everything is horizontally scalable on the database side. Do keep in mind, however, that Zabbix does still run in an Active/Passive setup.
I hope you enjoyed reading this blog post. If you have any questions or need help configuring anything in your Zabbix setup feel free to contact me and the team at Opensource ICT Solutions. We build a ton of cool stuff like this and more!
Longtime Crypto-Gram readers know that I collect personal experiences of people being scammed. Here’s an almost:
Then he added, “Here at Chase, we’ll never ask for your personal information or passwords.” On the contrary, he gave me more information—two “cancellation codes” and a long case number with four letters and 10 digits.
That’s when he offered to transfer me to his supervisor. That simple phrase, familiar from countless customer-service calls, draped a cloak of corporate competence over this unfolding drama. His supervisor. I mean, would a scammer have a supervisor?
The line went mute for a few seconds, and a second man greeted me with a voice of authority. “My name is Mike Wallace,” he said, and asked for my case number from the first guy. I dutifully read it back to him.
“Yes, yes, I see,” the man said, as if looking at a screen. He explained the situation—new account, Zelle transfers, Texas—and suggested we reverse the attempted withdrawal.
I’m not proud to report that by now, he had my full attention, and I was ready to proceed with whatever plan he had in mind.
It happens to smart people who know better. It could happen to you.
However, just after 12:30 UTC (17:00 local time), the Internet was completely shut down, with Afghani news outlet TOLOnews initially reporting in a post on X that “Sources have confirmed to TOLOnews that today (Monday), afternoon, fiber-optic Internet will be shut down across the country.” This shutdown is likely an extension of the regional shutdowns of fiber optic connections that took place earlier in September, and it will reportedly remain in force “until further notice”. (The earlier regional shutdowns are discussed in more detail below.)
While Monday’s first shutdown was only partial, with mobile connectivity apparently remaining available, the graphs below show that the second event took the country completely offline, with web and DNS traffic dropping to zero at a national level, as seen in the graphs below.
HTTP request traffic is traffic coming from web browsers, applications, and automated tools, and is a clear signal of the availability of Internet connectivity. The graph below shows this request volume dropping sharply as the shutdown was implemented.
HTTP request traffic from Afghanistan, September 29, 2025
Cloudflare sends bytes back in response to those HTTP requests (“HTTP bytes”), as well as sending bytes back in response to traffic associated with other services, such as our 1.1.1.1 DNS resolver, authoritative DNS, WARP, etc. (“total bytes”). Cloudflare stopped receiving client traffic from the services when the shutdown began, causing the bytes transferred in response to drop to zero.
Internet traffic from Afghanistan, September 29, 2025
1.1.1.1 is Cloudflare’s privacy-focused DNS resolver, and processes DNS lookup requests from clients. As connectivity was cut, traffic to the service disappeared.
DNS query traffic to Cloudflare’s 1.1.1.1 resolver from Afghanistan, September 29, 2025
At a regional level, it appears that traffic from Kabul fell slightly later than traffic from the other regions, trailing them by approximately a half hour.
HTTP request traffic from the top five provinces in Afghanistan, September 29, 2025
The delay in traffic loss seen in Kabul may be associated with a more gradual loss of traffic seen at AS38742 (Afghan Wireless), which saw traffic approach zero just after 13:00 UTC (17:30 local time). This conjecture is supported by a published report that noted “Residents across Kabul and several provincial cities reported on Monday that fiber-optic services were no longer available, with only limited mobile data functioning briefly before signal towers stopped working altogether.”
Interestingly, it appears that as of 00:00 UTC (04:30 local time) on September 30, we continue to see a very small amount of traffic from this network. (This is in contrast to other networks, whose lines disappeared from the graph around 12:30 UTC (17:00 local time)).
HTTP request traffic from the top 10 ASNs in Afghanistan, September 29, 2025
Network providers announce IP address space that they are responsible for to other networks, enabling the routing of traffic to and from those IP addresses. When these announcements are withdrawn, the resources in that address space, whether clients or servers, can no longer reach, or are no longer reachable from, the rest of the Internet.
In Afghanistan, announced IPv4 address space dropped rapidly as the shutdown was implemented, falling by two-thirds from 604 to 197 announced /24s (blocks of 256 IPv4 addresses) in the first 20 minutes, and then dropping further over the next 90 minutes. Through the end of the day, several networks continued to announce a small amount of IPv4 address space: four /24s from AS38742 (Afghan Wireless), two from AS149024 (Afghan Bawar ICT Services), and one each from AS138322 (Afghan Wireless) and AS136479 (Cyber Telecom).
Announced IPv4 address space from Afghanistan, September 29, 2025
Announced IPv6 address space fell as well, though not quite as catastrophically, dropping by three-fourths almost immediately, from 262,407 /48s (blocks of over 1.2 septillion IPv6 addresses) to 65,542.
Announced IPv6 address space from Afghanistan, September 29, 2025
Regional shutdowns by the Taliban to prevent “immoral activities”
In mid-September, the Taliban ordered the shutdown of fiber optic Internet connectivity in multiple provinces across Afghanistan, as part of a drive to “prevent immorality”. It was the first such ban issued since the Taliban took full control of the country in August 2021.
These regional shutdowns blocked Afghani students from attending online classes, impacted commerce and banking, and limited access to government agencies and institutions such as passport and registration offices, customs offices. As many as 15 provinces experienced shutdowns, and we review the observed impacts across several of them below, using the regional traffic data recently made available on Cloudflare Radar.
Balkh appeared to be one of the earliest targeted provinces, with traffic dropping midday (UTC) on September 15. While some nominal recovery occurred on September 23, traffic remained well below pre-shutdown levels.
Internet traffic from Balkh, Afghanistan, September 1-28, 2025
After several days of peak traffic levels double those seen in previous weeks, traffic in Takhar fell on September 16, remaining near zero until September 21, when a small amount of connectivity was apparently restored.
Internet traffic from Takhar, Afghanistan, September 1-28, 2025
In Kandahar, lower peak traffic volumes are visible between September 17 and September 21. The partial restoration of traffic is coincident with the restoration of Internet services highlighted in a published report, though it notes that “The restoration of services is limited to point-to-point connections for key government offices, including banks, customs offices, and the Directorate for National ID Cards.”
Internet traffic from Kandahar, Afghanistan, September 1-28, 2025
Baghlan experienced an anomalous spike in traffic on September 16, with total traffic spiking 3x higher than peaks seen during the previous weeks. However, on September 17, traffic dropped to a fraction of pre-shutdown levels. Except for a return to near-normal levels on September 21 & 22, the disruption remained in place through the end of the month.
Internet traffic from Baghlan, Afghanistan, September 1-28, 2025
Traffic in Nangarhar was disrupted between September 19-22, but quickly recovered to pre-shutdown levels once restored.
Internet traffic from Nangarhar, Afghanistan, September 1-28, 2025
After experiencing an apparent issue at the start of the month, Internet traffic in Oruzgan, again fell on September 19. After an apparent complete shutdown, on September 23, a small amount of traffic was again visible.
Internet traffic from Oruzgan, Afghanistan, September 1-28, 2025
Internet connectivity was also disrupted in the province of Herat, although differently. From September 22-25, partial Internet outages were implemented between 16:30-03:30 UTC (21:00-08:00 local time), with traffic volumes dropping to approximately half of those seen at the same time the prior weeks. The intent of these “Internet curfew” shutdowns is unclear, but Herat residents noted that they “severely disrupted their business and educational activities”.
Internet traffic from Herat, Afghanistan, September 16-29, 2025
While Internet shutdowns remain all too common around the world, most (though not all) are comparatively short-lived, and are generally in response to a local event, such as exams, unrest/riots, elections, etc. Given the broad impact of this shutdown across all facets of daily personal, social, and professional life in Afghanistan, analysts state that it “could deepen Afghanistan’s digital isolation, further damage its struggling economy and drive more Afghans out of work at a time when humanitarian needs are already severe.”
Artificial intelligence (AI) tools are shaping our world in many ways. Helping young people develop AI literacy — in other words, helping them understand how AI tools work and how to use them responsibly — is essential.
At the Raspberry Pi Foundation, we’re committed to empowering educators around the world with everything they need to teach AI confidently and help young people develop AI literacy. That’s why we developed Experience AI: a set of high-quality AI literacy resources designed in collaboration with Google DeepMind that any educator can use, no matter their level of tech knowledge.
We’re excited to introduce a new addition to the Experience AI resources: AI Quests.
Enter AI Quests
Developed by Google Research in collaboration with the Stanford Accelerator for Learning, AI Quests is a browser-based learning experience that lets students step into the role of AI researchers. Through interactive, story-driven activities, they’ll explore essential AI topics such as:
Data preparation
Testing and evaluation
Bias in AI systems
Students will use what they learn about these topics to tackle simulated global challenges. The first quest, Market Marshes, introduces them to how AI technology can be used in flood forecasting, while upcoming quests will explore other real-world issues.
Why AI Quests matters
AI technology is frequently used but often poorly understood. AI Quests, like Experience AI more broadly, gives students practical experience of how AI technology works, and shows why it’s so important.
Here’s what sets AI Quests apart:
Gamified learning: Storytelling and role play turn abstract ideas into immersive experiences
Real-world relevance: Students see how AI technology addresses challenges like climate resilience and health equity
No prior knowledge required: Any teacher, regardless of subject specialism, can bring AI Quests into their classroom
Developed by experts: Built with Google Research and the Stanford Accelerator for Learning, content is high-quality and credible
What’s next
AI Quests is launching in English, with future plans for translations and additional quests to reach even more learners globally.
To support educators, we’re also hosting two free webinars on YouTube and LinkedIn:
9 October at 4pm BST
16 October at 4pm BST
These sessions will walk you through AI Quests, offer classroom tips, and give you the chance to ask questions directly.
AI literacy is one of the most valuable skills young people can develop today. With this new addition to Experience AI, we’re making it even more engaging, practical, and accessible for classrooms everywhere.
Security updates have been issued by Debian (python-internetarchive and tiff), Fedora (nextcloud), Oracle (kernel, openssh, and squid), Red Hat (kernel, kernel-rt, and ncurses), SUSE (afterburn and chromium), and Ubuntu (open-vm-tools, ruby-rack, and tiff).
After marking bcachefs “externally maintained” in 6.17, Linus Torvalds has removed
it entirely for 6.18. “It’s now a DKMS module, making the in-kernel
code stale, so remove it to avoid any version confusion.“
Search technology, specifically web search technology, has been around for more than 30 years. You entered a few words in a text box, clicked “Search,” and received a series of links. However, the results were often a mix of related, non-related, and general links. If the results didn’t contain the information you needed, you reformulated your query and submitted it to the search engine again. Some of the breakdowns occurred around language—the text you matched was missing some context that disambiguated your search terms. Other breakdowns were conceptual in nature—you made inferences yourself that led you to new, successful search terms. In all cases, you were the agent that adjusted your search until you received the right information in response. Search engines fail to understand context, so you had to act as translators between your information needs and the rigid keyword system.
With the advent of natural language models like large language models (LLMs) and foundation models (FMs), AI-powered search systems are able to incorporate more of the searcher’s intelligence into the application, relieving you of some of the burden of iterating over search results. On the search side, application designers can choose to employ semantic, hybrid, multimodal, and sparse search. These methods use LLMs and other models to generate a vector representation of a piece of text and a query to provide nearest-neighbor matching. On the application side, application designers are employing AI agents embedded in workflows that can make multiple passes over the search system, rewrite user queries, and rescore results. With these advances, searchers expect intelligent, context-aware results.
As user interactions become more nuanced, many organizations are enhancing their existing search capabilities with intent-based understanding. The emergence of language models that create vector embeddings brings opportunities to further enhance search systems by combining traditional relevancy algorithms with semantic understanding. This hybrid approach allows applications to better interpret user intent, handle natural language variations, and deliver more contextually relevant results. By integrating these complementary capabilities, organizations can build upon their robust search infrastructure to create more intuitive and responsive search experiences that understand the keywords and also the reason behind the query.
This post describes how organizations can enhance their existing search capabilities with vector embeddings using Amazon OpenSearch Service. We discuss why traditional keyword search falls short of modern user expectations, how vector search enables more intelligent and contextual results, and the measurable business impact achieved by organizations like Amazon Prime Video, Juicebox, and Amazon Music. We examine the practical steps for modernizing search infrastructure while maintaining the precision of traditional search systems. This post is the first in a series designed to guide you through implementing modernized search applications, using technologies such as vector search, generative AI, and agentic AI to create more powerful and intuitive search experiences.
Going beyond keyword search
Keyword-based search engines remain essential in today’s digital landscape, providing precise results for product matching and structured queries. Although these traditional systems excel at exact matches and metadata filtering, many organizations are enhancing them with semantic capabilities to better understand user intent and natural language variations. This complementary approach allows search systems to maintain their foundational strengths while adapting to more diverse search patterns and user expectations. In practice, this leads to several business-critical challenges:
Missed opportunities and inefficient discovery – Traditional search approaches tend to oversimplify user intent, grouping diverse search behaviors into broad categories. When Amazon Prime Video users searched for “live soccer,” the search results included documentaries like “This is Football: Season 1”; users were seeing irrelevant results that were keyword matches, but missed the context encoded in “live” as a keyword.
Inability to adapt to changing search behavior – Search behavior is evolving rapidly. Users now employ conversational language, ask full questions, and expect systems to understand context and nuance. Juicebox encountered this challenge with recruiting search engines that relied on simple Boolean or keyword-based searches, and couldn’t capture the nuance and intent behind complex recruiting queries, leading to large volumes of irrelevant results.
Limited personalization and contextual understanding – Search engines can be enhanced with personalization capabilities through additional investment in technology and infrastructure. For example, Amazon Music improved its recommendation system by augmenting traditional search capabilities with personalization features, allowing the service to consider user preferences, listening history, and behavioral patterns when delivering results. This demonstrates how organizations can build upon fundamental search functionality to create more tailored experiences when specific use cases warrant the investment.
Hidden business impact of poor search – Inefficient search also has measurable business impacts. For instance, Juicebox recruiters were spending unnecessary time filtering through irrelevant results, making the process time-consuming and inefficient. Amazon Prime Video discovered that their original search experience, designed for movies and TV shows, wasn’t meeting the needs of sports fans, creating a disconnect between search queries and relevant results.
Importance of building modern search applications
Organizations are at a pivotal moment in enterprise search evolution. User interactions with information are fundamentally changing and analysts predict that the shift from traditional search interactions to AI-powered interfaces will continue to accelerate through 2026, as users increasingly expect more conversational and context-aware experiences. This transformation reflects evolving user expectations for more intuitive, intent-driven search experiences that understand not just what users type, but what they mean.
Real-world implementations demonstrate the tangible value of enhancing existing search. Examples like Amazon Prime Video and Juicebox demonstrate how semantic understanding and augmenting traditional search with vector capabilities can improve performance and increase end-customer satisfaction. The ability to deliver personalized, context-aware search experiences is becoming a key differentiator in today’s digital landscape.
Although organizations recognize these opportunities, many seek guidance on practical implementation. Successful organizations are taking a complementary approach by enhancing their proven search infrastructure with vector capabilities rather than replacing existing systems. Organizations can deliver more sophisticated search experiences that meet both current and future user needs, combining traditional search precision with semantic understand. The path forward isn’t about replacing existing search systems but enhancing them to create more powerful, intuitive search experiences that drive measurable business value.
Transforming business value and user experiences with vector search
Building upon the strong foundation of traditional search systems, businesses are expanding their search functionality to support more conversational interactions and diverse content types. Vector search complements existing search capabilities, helping organizations extend their search experiences into new domains while maintaining the precision and reliability that traditional search provides. This combination of proven search technology with emerging capabilities creates opportunities for more dynamic and interactive user experiences.
If you’re using OpenSearch Service to power your keyword search, you’re already using a scalable, reliable solution. Juicebox’s migration to vector search reduced query latency from 700 milliseconds to 250 milliseconds while surfacing 35% more relevant candidates for complex queries. Despite handling a massive database of 800 million profiles, the system maintained high recall accuracy and delivered aggregation queries across 100 million profiles. Amazon Music’s success story further reinforces the scalability of vector search solutions. Their recommendation system now efficiently manages 1.05 billion vectors, handling peak loads of 7,100 vector queries per second across multiple geographies to power real-time music recommendations for their vast catalog of 100 million songs.
How vector embeddings transform user experience
Consumers increasingly rely on digital platforms and apps to quickly discover healthy and delicious meal options, especially as busy schedules leave little time for meal planning and preparation. For organizations building these applications, the traditional keyword-based search approach often falls short in delivering the most relevant results to their users. This is where vector search, powered by embeddings and semantic understanding, can make a significant difference.
Imagine you’re a developer at an ecommerce company building a food delivery app for your customers. When a user enters a search query like “Quick, healthy dinner with tofu, no dairy,” a traditional keyword-based search would only return recipes that explicitly contain those exact words in the metadata. This approach has several shortcomings:
Missed synonyms – Recipes labeled as “30-minute meals” instead of “quick” would be missed, even though they match the user’s intent.
Lack of semantic understanding – Dishes that are healthy and nutrient-dense, but don’t use the word “healthy” in the metadata, would not be surfaced. The search engine lacks the ability to understand the semantic relationship between “healthy” and nutritional value.
Inability to detect absence of ingredients – Recipes that don’t contain dairy but don’t explicitly state “dairy-free” would also be missed. The search engine can’t infer the absence of an ingredient.
This limitation means organizations miss valuable opportunities to delight their users and keep them engaged. Imagine if your app’s search function could truly understand the user’s intent, by correlating that “quick” refers to meals under 30 minutes, “healthy” relates to nutrient density, and “no dairy” means excluding ingredients like milk, butter, or cheese. This is precisely where vector search powered by embeddings and semantic understanding can transform the user experience.
Conclusion
This post covered key concepts and business benefits of incorporating vector search into your existing applications and infrastructure. We discussed the limitations of traditional keyword-based search and how vector search can significantly improve user experience. Vector search, powered by generative AI, can detect relevant attributes, better infer the presence or absence of specific criteria, and surface results that better align with user intent, whether your users are searching for products, recipes, research, or knowledge.
Modernizing your search capabilities with vector embeddings is a strategic move that can drive engagement, improve satisfaction, and deliver measurable business outcomes. By taking incremental steps to integrate vector search, your organization can future-proof its applications and stay ahead in an ever-evolving digital landscape.
Our next post will dive into Automatic Semantic Enrichment. We discuss how to generate semantic embeddings using Amazon Bedrock, set up vector-based indexes in OpenSearch Service, and combine vector and keyword search for even more relevant results. We provide step-by-step guidance and sample code to help you enhance your OpenSearch Service infrastructure with vector search, so your users can discover and engage with your data in more meaningful ways.
To learn more, refer to Amazon OpenSearch Service as a Vector Database, and visit our Migration Hub if you’re looking for migration and system modernization guidance and resources. For more blog posts about vector databases, refer to the AWS Big Data Blog. The following posts can help you learn more about vector database best practices and OpenSearch Service capabilities:
The 6.17 development cycle ended on September 28 with the release
of the 6.17 kernel. This cycle brought in 13,089 non-merge changesets, a
slowdown from its predecessor but still within the normal bounds for recent
kernels. The time has come for a look at where those changes came from,
with a bit of a side trip into bug statistics.
As generative AI becomes foundational across industries—powering everything from conversational agents to real-time media synthesis—it simultaneously creates new opportunities for bad actors to exploit. The complex architectures behind generative AI applications expose a large surface area including public-facing APIs, inference services, custom web applications, and integrations with cloud infrastructure. These systems are not immune to classic or emerging external threats. We have introduced a series of posts on securing generative AI, starting with Securing generative AI: An introduction to the Generative AI Security Scoping Matrix, which establishes a model for the risk and security implications based on the type of generative AI workload you are deploying and lays the foundation for the rest of our series.
This post continues the series, and provides guidance on how to build secure, scalable network architectures for generative AI applications on Amazon Web Services (AWS) through a defense-in-depth approach. You’ll learn how to protect your AI workloads while maintaining performance and reliability. We cover multiple security layers including virtual private cloud (VPC) isolation, network firewalls, application protection, and edge security controls that you can use to create a comprehensive defense strategy for generative AI workloads.
Common generative AI external threats
In this section, we review some of the most common external threats facing generative AI applications today.
Network level DDoS attacks (layer 4)
Network level distributed denial-of-service (DDoS) or volumetric attacks such as SYN floods, UDP floods, and ICMP floods, target the network layer by sending a flood of layer 4 requests to a server. The aim is to exhaust the server’s resources by initiating multiple half-open layer 4 connections, ultimately rendering the system unresponsive to legitimate users. For generative AI applications, which often require sustained sessions and low-latency responses, such exploits can severely disrupt availability and user experience. Another type of volumetric attack is reflection attacks, where threat actors exploit services such as DNS to amplify the volume of traffic sent to a target. A small request sent to a vulnerable third-party server is reflected and expanded into a large response directed at the victim. This technique is particularly dangerous when generative AI APIs are exposed to the public internet, because it can flood the endpoints with unexpected traffic, causing service degradation.
Web request flood (layer 7)
These sophisticated exploits on layer 7 mimic legitimate traffic patterns to evade traditional security filters. By overwhelming application endpoints with excessive HTTP requests, bad actors can cause compute exhaustion, especially in inference-heavy AI workloads. Unlike volumetric DDoS, these requests are often hard to distinguish from real users, making mitigation more complex.
Application-specific exploits
Bad actors increasingly focus on exploiting vulnerabilities in application-specific code or the systems on which the code runs—such as Apache, Nginx, or Tomcat. For generative AI applications, which often involve custom APIs and orchestration layers, even a small misconfiguration or unpatched component can open the door to unauthorized access, data leakage, or system compromise.
SQL injection
By injecting malicious SQL code through input fields or query parameters, bad actors can manipulate backend databases to exfiltrate or corrupt data. Generative AI apps that log prompts or store user interactions are especially susceptible if input sanitization is not enforced rigorously.
Cross-site scripting
Cross-site scripting (XSS) attacks involve injecting malicious scripts into trusted web pages. When unsuspecting users interact with these scripts, bad actors can hijack sessions, steal data, or redirect users to malicious sites. Frontend interfaces for AI services, especially dashboards or prompt consoles, are particularly vulnerable.
OWASP top application security risks
The OWASP Top 10 serves as a critical framework for identifying common security risks in web applications. These include issues such as broken access control, security misconfigurations, and insufficient logging and monitoring. Generative AI solutions must adhere to OWASP guidelines to mitigate the broader landscape of web application threats.
Common vulnerabilities and exposures
Security professionals must remain vigilant to known common vulnerabilities and exposures (CVEs) impacting AI stack components—ranging from open-source libraries to model-serving infrastructure. Ignoring CVEs can lead to exploits that compromise sensitive model outputs, internal APIs, or user data.
Malicious bots and crawlers
Malicious bots increasingly target AI applications to scrape content such as generated text, pricing data, proprietary models, or images behind paywalls. These bots can masquerade as legitimate crawlers or scanners but are designed to harvest content at scale, potentially violating terms of service and impacting infrastructure costs.
Content scrapers and probing tools
Automated tools that crawl, scrape, or scan generative AI systems are often used for competitive intelligence, model inversion, or discovering exposed endpoints. These tools can weaken privacy guarantees and expose AI behavior to unintended third parties.
Securing your generative AI applications
Here are some of the common strategies that you can use to help secure your generative AI applications using AWS services.
Private networking with Amazon Bedrock
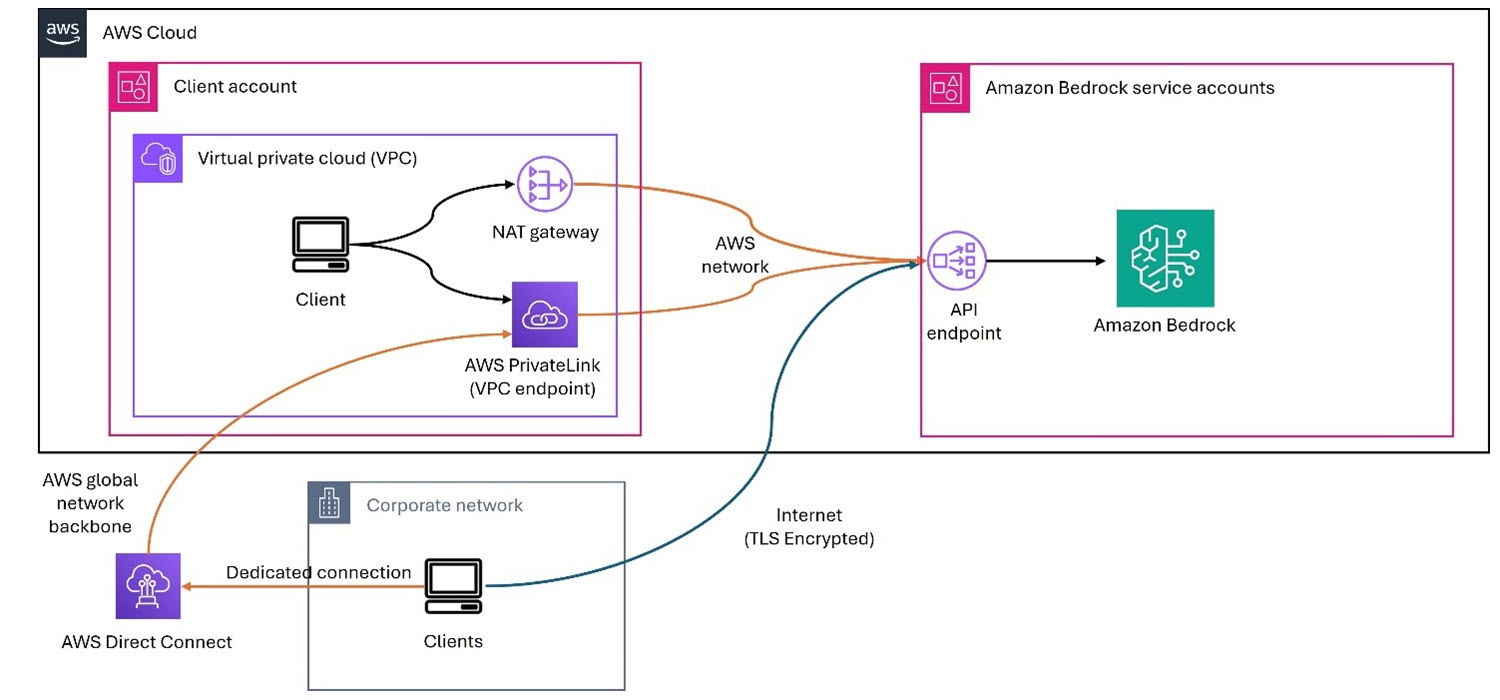
Amazon Bedrock is a fully managed service provided by AWS that offers developers access to foundation models (FMs) and the tools to customize them for specific applications. Developers can use it to build and scale generative AI applications using FMs through an API, without managing infrastructure. A typical set of environments is shown in Figure 1. It has the following network components:
The Amazon Bedrock service accounts, which hold the service components and exposes its API endpoint within the same AWS Region as the customer’s account.
The customer’s AWS account, from which the application needs to use Amazon Bedrock and invokes the Amazon Bedrock API with the query request.
The customer’s corporate network within the existing data center, which is external to the AWS global network, and holds the customer’s application that also needs to use Amazon Bedrock and can involve the Amazon Bedrock API request. AWS Direct Connect provides a dedicated network connection between an on-premises network and AWS, bypassing the public internet.
Figure 1 – Private networking architecture with Amazon Bedrock
You can use AWS PrivateLink to establish private connectivity between the FMs and the generative AI applications running in on-premises networks or your Amazon Virtual Private Cloud (Amazon VPC), without exposing your traffic to the public internet. In the case of Amazon VPC, the application running on the private subnet instance invokes the Amazon Bedrock API call. The API call is routed to the Amazon Bedrock VPC endpoint that is associated to the VPC endpoint policy and then to Amazon Bedrock APIs. The Amazon Bedrock service API endpoint receives the API request over PrivateLink without traversing the public internet. You also have the option of connecting to the Amazon Bedrock service API through the NAT Gateway. Note that in this case, the traffic goes over the AWS network backbone without being exposed to the public internet.
You can also privately access Amazon Bedrock APIs over the VPC endpoint from your corporate network through an AWS Direct Connect gateway. In case you don’t have Direct Connect, you can connect to the Amazon Bedrock service API over public internet (shown by the lower arrow in figure 1). In each of these cases, traffic to the API endpoint for Amazon Bedrock is encrypted in flight using TLS 1.2 or later, and traffic within the Amazon Bedrock service is also encrypted in flight to at least this standard. Customer content processed by Amazon Bedrock is encrypted and stored at rest in the Region where you are using Amazon Bedrock.
Minimize layer 7 generative AI threats with AWS WAF
As generative AI systems become integral to content creation, customer service, and decision-making processes, they are increasingly targeted by malicious bot threats. These exploits can distort outputs, flood models with biased or harmful training data (data poisoning), exploit vulnerabilities for prompt injection, or overwhelm systems through automated abuse. The consequences include degraded model performance, spread of misinformation, compromised data privacy, and erosion of user trust. To mitigate these threats, safeguards such as user authentication, input validation, anomaly detection, and continuous monitoring must be embedded into generative AI pipelines. AWS WAF is a web application firewall that helps protect applications (OSI Layer 7) from bot exploits by using intelligent detection and rule-based defenses. Its Bot Control feature identifies and filters out harmful bots while allowing legitimate ones. Through rate limiting, custom rules, and anomaly detection, AWS WAF can block scraping, credential stuffing, and distributed denial-of-service attempts (DDoS). Anti-DDoS rule group—targeted specifically at automatic mitigation of application exploits that involve HTTP request floods—is available as a Managed Rules group through AWS WAF. It removes the complexity associated with managing various AWS WAF rules and ACLs to handle these increasingly agile threats.
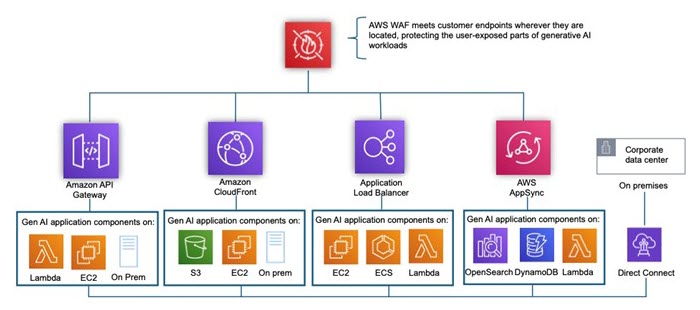
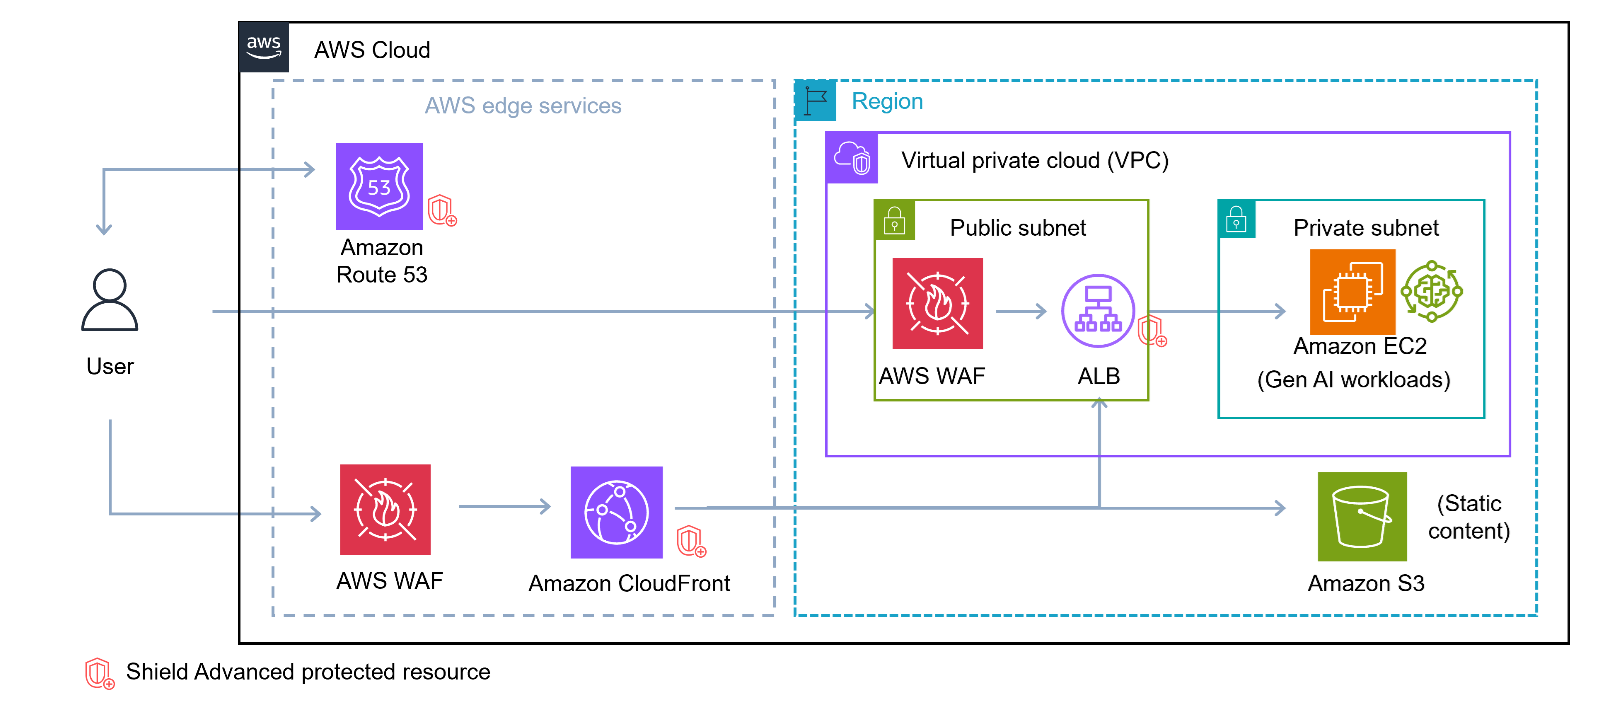
AWS WAF can be enabled on Amazon CloudFront, Amazon API Gateway, Application Load Balancer (ALB) and is deployed alongside these services (Figure 2). These AWS services terminate the TCP/TLS connection, process incoming HTTP requests, and then forward the request to AWS WAF for inspection and filtering. There is no need for reverse proxy, DNS setup, or TLS certification.
Figure 2 – Architecture using AWS WAF to minimize layer 7 generative AI threats
Mitigate DDoS at the edge for generative AI applications
DDoS attacks pose a serious threat to generative AI applications by overwhelming servers with massive traffic, leading to latency, degraded performance, or complete outages. Because generative AI workloads are often resource-intensive and operate in real time (for example, chatbots, image generators, and coding assistants), even brief disruptions can impact user experience and trust. Moreover, DDoS attacks can be used as a smokescreen for other exploits, such as data exfiltration or prompt injection. Protecting generative AI systems with scalable defenses such as rate limiting, traffic filtering, and auto-scaling infrastructure is crucial to help maintain availability and service continuity.
AWS Shield safeguards generative AI applications from DDoS attacks by providing always-on detection and automated mitigation. The standard tier, AWS Shield Standard, defends against common volumetric and state-exhaustion attacks with no additional cost. For advanced protection, AWS Shield Advanced offers real-time threat intelligence, adaptive rate limiting, and 24/7 access to the AWS Shield Response Team (SRT). To use the services of the SRT, you must be subscribed to the Business Support plan or the Enterprise Support plan. This helps makes sure that generative AI services—often reliant on high availability and low latency—remain resilient under threat, maintaining performance and uptime even during large-scale traffic surges. Integration with services like Amazon CloudFront and Elastic Load Balancing further enhances scalability and protection (Figure 3).
Figure 3 – Help protect your applications from DDoS attack by using AWS Shield Advance at the edge
Perimeter firewall for generative AI applications
AWS Network Firewall is a managed network security service that you can use to deploy stateful and stateless packet inspection, intrusion prevention (IPS), and domain filtering capabilities directly into your Amazon VPCs. It helps inspect and filter both inbound and outbound traffic at the subnet level. For generative AI applications, this means enforcing fine-grained traffic controls without the complexity of managing your own appliances or proxies. You can use AWS Network Firewall to create custom stateless or stateful rules to block specific payloads, known signatures, or unusual traffic patterns. In multi-model or multi-tenant environments, the firewall can help enforce east-west segmentation, so that a compromised microservice cannot laterally access other AI components or sensitive services. Network Firewall can also be effective in collecting hostnames of the specific sites that are being accessed by your generative AI application. This process is called egress filtering and is specifically helpful in case an adversary compromises the generative AI workload and tries to establish a connection to an external command and control system. Network Firewall can be used to help secure outbound traffic by blocking packets that fail to meet certain security requirements.
Monitor for malicious activity
Monitoring for malicious activity is essential to protect generative AI applications from evolving security threats. These applications process unpredictable user inputs and generate dynamic outputs, making them particularly vulnerable to exploitation. Continuous monitoring enables early detection of unusual traffic patterns, excessive API usage, or anomalous input behavior, symptoms which might indicate potential exploits. It also helps prevent misuse of AI models through prompt injection, adversarial inputs, or attempts to extract sensitive information from model responses. In addition, monitoring plays a critical role in identifying DDoS attempts and resource abuse, which could otherwise disrupt the availability of AI services. By observing and analyzing real-time activity, organizations can take proactive steps to block malicious actors, adjust security controls, and maintain the integrity and reliability of their generative AI applications. Amazon GuardDuty, a threat detection service, continuously analyzes AWS account activity, network flow logs, and DNS queries to uncover potential compromises or malicious behaviors targeting your environment. GuardDuty identifies suspicious activity such as AWS credential exfiltration and suspicious user API usage in Amazon SageMaker APIs. Additionally, GuardDuty offers protection plans for Amazon Simple Storage Service (Amazon S3), Amazon Relational Database Service (Amazon RDS), Amazon Elastic Kubernetes Service (Amazon EKS), EKS Runtime Monitoring, Runtime Monitoring for Amazon ECS and Amazon EC2, Malware Protection for Amazon EC2 and S3, and AWS Lambda Protection. Amazon Inspector is an automated vulnerability management service that continually scans AWS workloads for software vulnerabilities and unintended network exposure. Amazon Detective simplifies the investigative process and helps security teams conduct faster and more effective forensic investigations.
Network defense in depth for generative AI
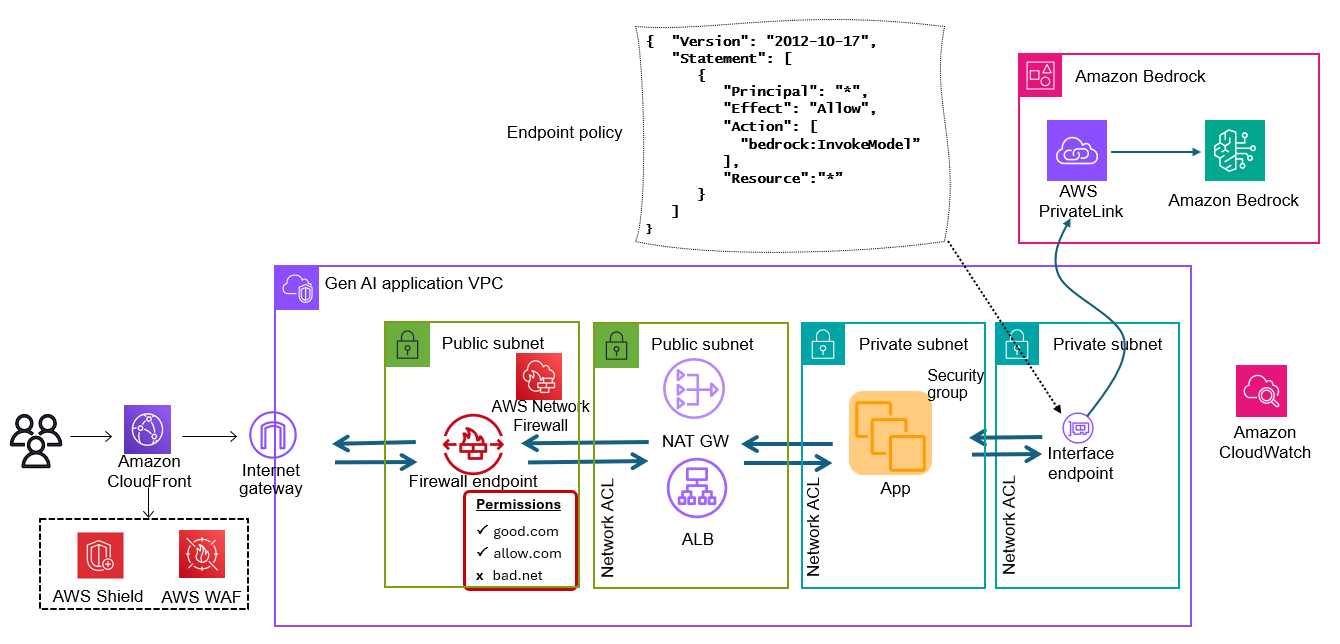
Like other modern applications, a defense-in-depth approach is recommended when designing network architectures for generative AI applications. A complete reference architecture of a generative AI application showing defense in depth protection using AWS services is shown in Figure 4.
Figure 4 – Workflow for generative AI network defense in depth
The workflow shown in Figure 4 is as follows:
A client makes a request to your application. DNS directs the client to a CloudFront location, where AWS WAF and Shield are deployed.
CloudFront sends the request through an AWS WAF rule to determine whether to block, monitor, or allow the traffic. Shield can mitigate a wide range of known DDoS attack vectors and zero-day attack vectors. Depending on the configuration, Shield Advanced and AWS WAF work together to rate-limit traffic coming from individual IP addresses. If AWS WAF or Shield Advanced don’t block the traffic, the services will send it to the CloudFront routing rules.
CloudFront sends the traffic to the ALB. However, before reaching the ALB, the traffic is inspected through a Network Firewall endpoint. Network Firewall supports deep packet inspection to decrypt, inspect, and re-encrypt inbound and outbound TLS traffic destined for the Internet, another VPC, or another subnet to help protect data. You can limit access to threat actors at this stage with additional safeguards. If you are not expecting traffic from high risk countries, it is advisable to restrict access through geographic blocking or you could at least put a strict rate limit for those countries where you don’t expect traffic through AWS WAF rules on ingress and Network Firewall on egress.
Note: If you use Amazon CloudFront geographic restrictions to block a country’s access to your content, then CloudFront blocks every request from that country. CloudFront doesn’t forward the requests to AWS WAF. To use AWS WAF criteria to allow or block requests based on geography, use an AWS WAF geographic match rule statement instead.
The ALB is in a public subnet. To keep the instances that run your app isolated from the rest of the world using the ALB, you can additionally, help protect from common layer 7 exploits with AWS WAF.
The ALB has target groups in the form of instances that are running the generative AI application running in a private subnet. You can help protect the instances and their network interfaces with the foundational VPC constructs like security groups, network ACLs (NACLs), and segmentation.
The application calls the Amazon Bedrock API. You can use PrivateLink to create a private connection between your VPC and Amazon Bedrock. You can then access Amazon Bedrock as if it were in your VPC, without the use of an internet gateway, NAT device, VPN connection, or Direct Connect connection. Instances in your VPC don’t need public IP addresses to access Amazon Bedrock. You establish this private connection by creating an interface endpoint, powered by PrivateLink. You create an endpoint network interface in each subnet that you enable for the interface endpoint. These are requester-managed network interfaces that serve as the entry point for traffic destined for Amazon Bedrock.
Create an interface endpoint for Amazon Bedrock using either the Amazon VPC console or the AWS Command Line Interface (AWS CLI). Create an interface endpoint for Amazon Bedrock using the following service name: com.amazonaws.region.bedrock-runtime
Create an endpoint policy for your interface endpoint. An endpoint policy is an AWS Identity and Access Management (IAM) resource that you can attach to an interface endpoint. The default endpoint policy allows full access to Amazon Bedrock through the interface endpoint. To control the access allowed to Amazon Bedrock from your VPC, attach a custom endpoint policy to the interface endpoint. An example of a custom endpoint policy is shown in Figure 4. When you attach this policy to your interface endpoint, it grants access to the listed Amazon Bedrock actions for all principals on all resources.
This solution uses Amazon CloudWatch to collect operational metrics from various services to generate custom dashboards that you can use to monitor the deployment’s performance and operational health.
The return flow of the traffic traverses the same path in reverse direction.
Conclusion
In this post, we reviewed the secure network design principles that provide a robust foundation for deploying generative AI applications on AWS while maintaining strong security controls. By implementing the patterns described in this post, you can confidently use AI capabilities while protecting sensitive data and infrastructure.
Want to dive deeper into additional areas of generative AI security? Check out the other posts in the Securing generative AI series:
Part 1 – Securing generative AI: An introduction to the generative AI Security Scoping Matrix
Part 2 – Designing generative AI workloads for resilience
Part 3 – Securing generative AI: Applying relevant security controls
Part 4 – Securing generative AI: data, compliance, and privacy considerations
Part 5 – Build secure network architectures for generative AI applications using AWS services (this post)
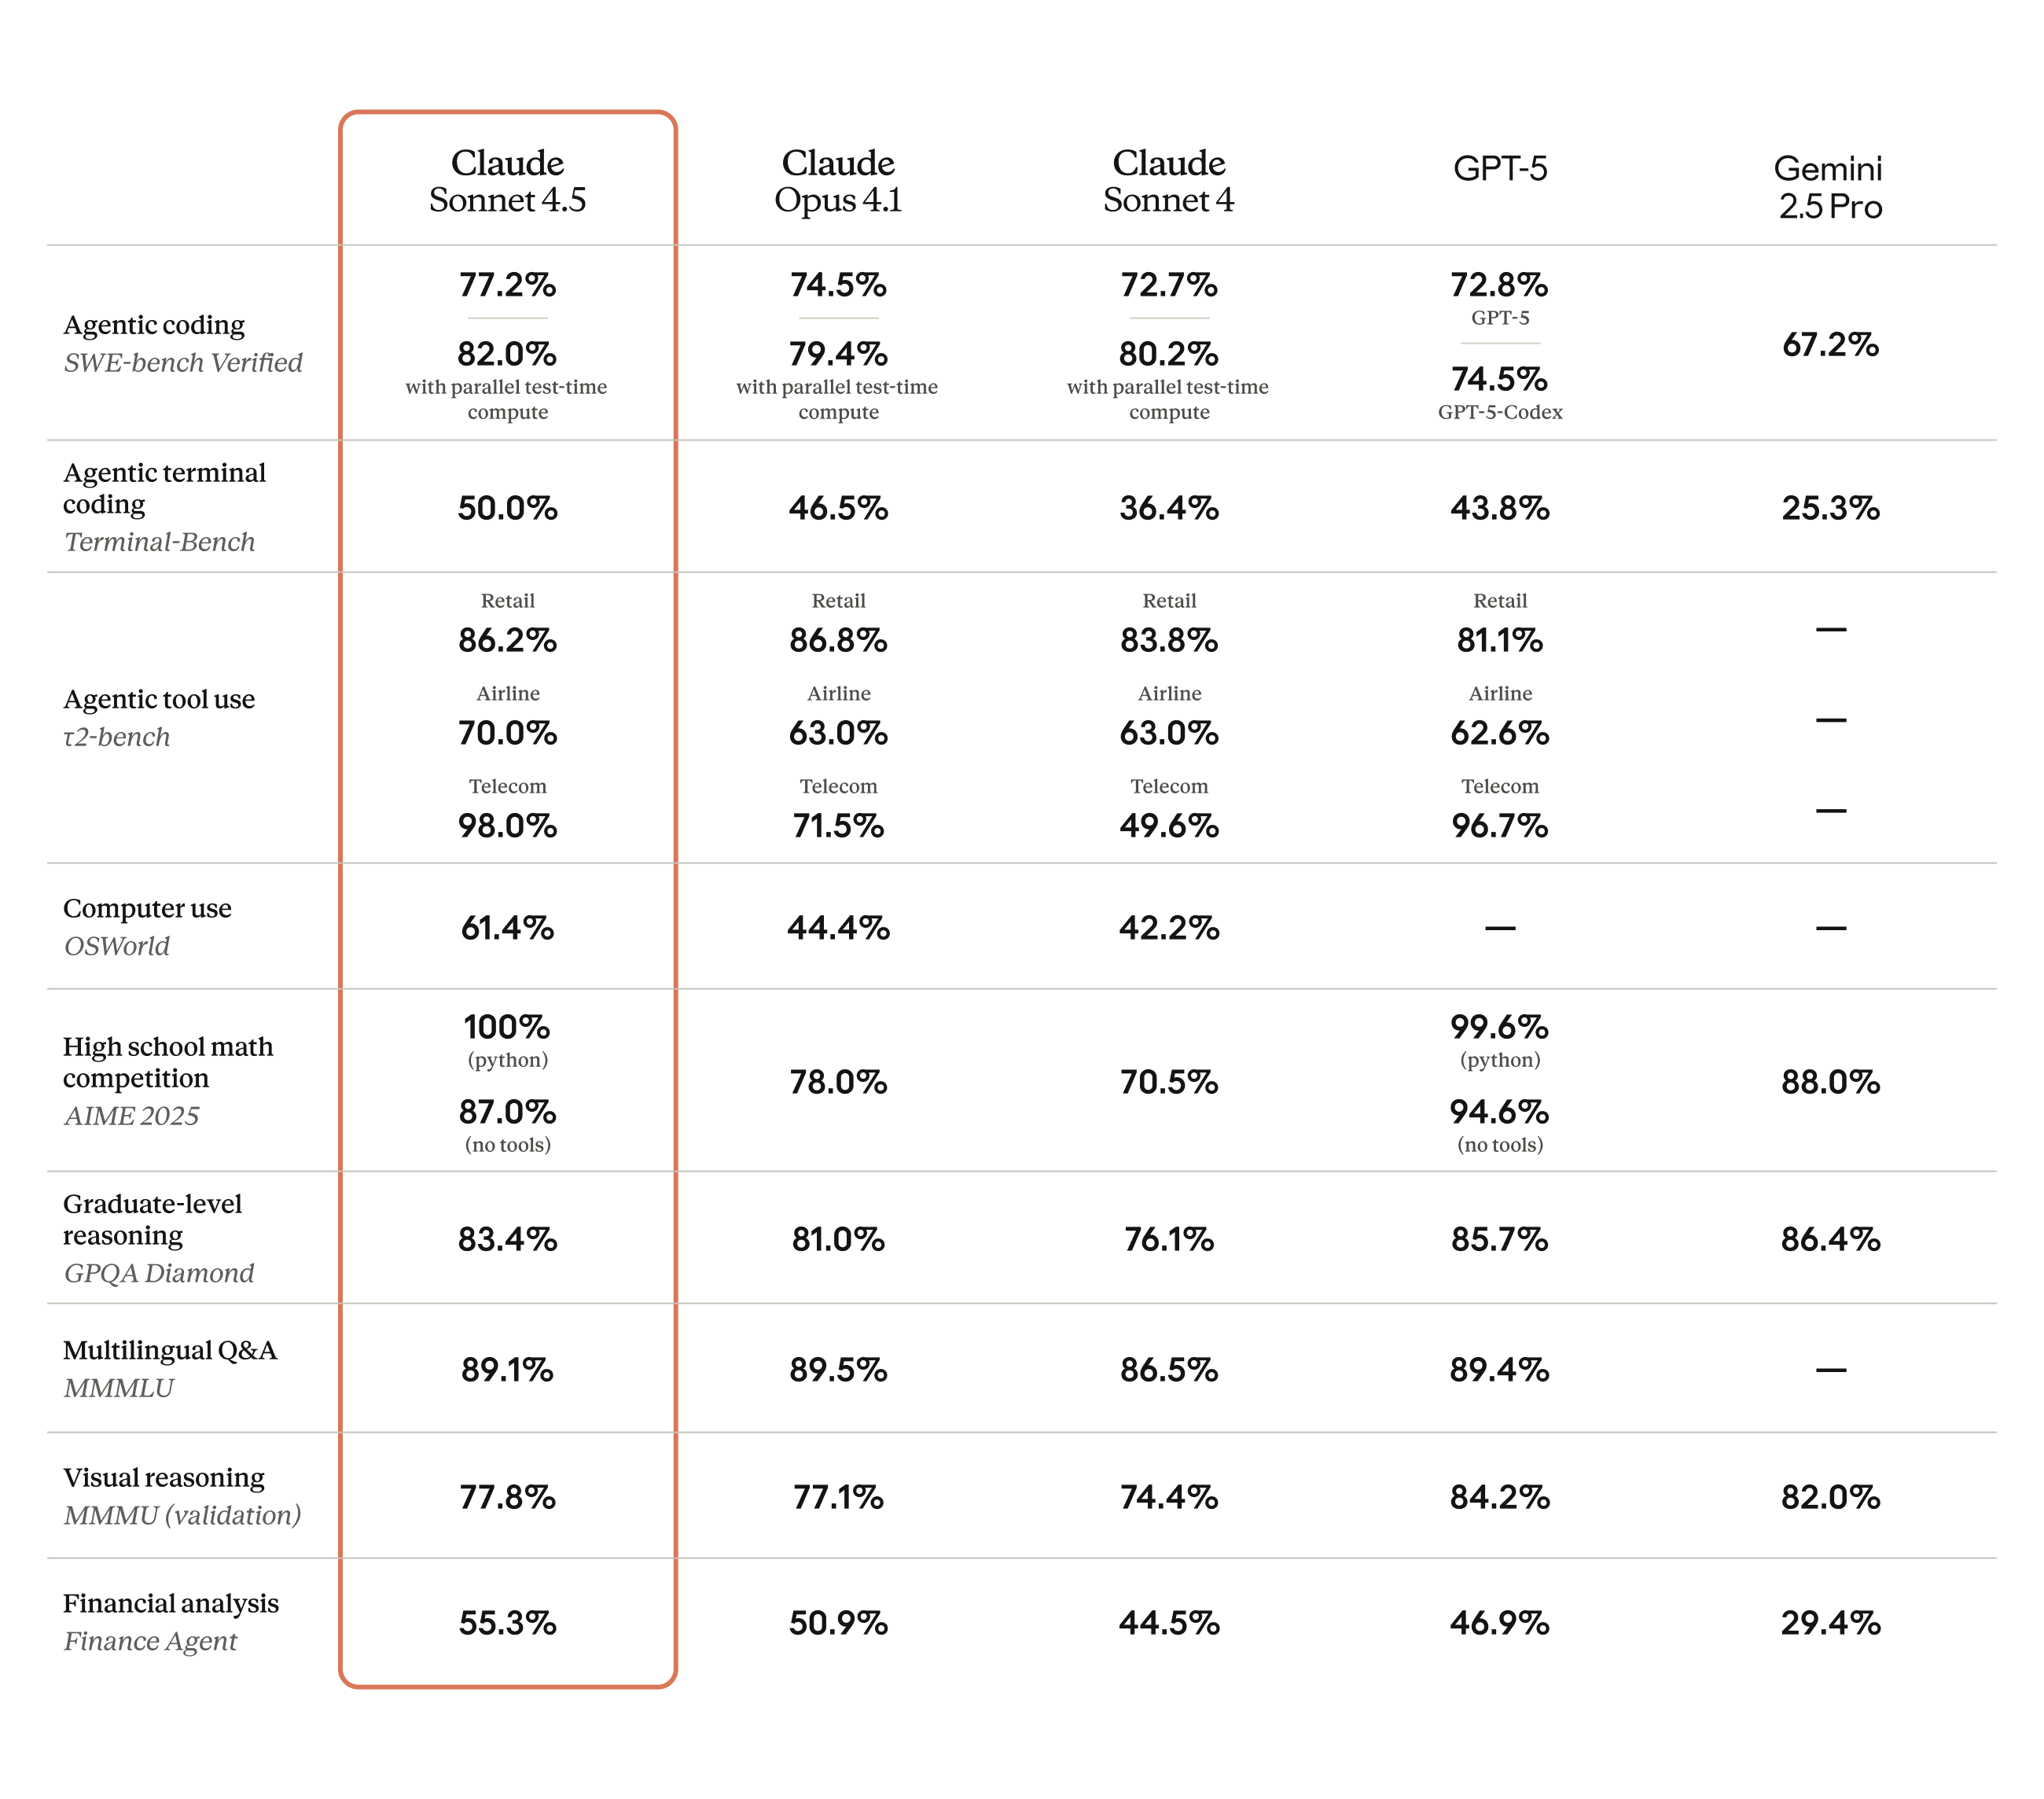
Today, we’re excited to announce that Claude Sonnet 4.5, powered by Anthropic, is now available in Amazon Bedrock, a fully managed service that offers a choice of high- performing foundation models from leading AI companies. This new model builds upon Claude 4’s foundation to achieve state-of-the-art performance in coding and complex agentic applications.
Claude Sonnet 4.5 demonstrates advancements in agent capabilities, with enhanced performance in tool handling, memory management, and context processing. The model shows marked improvements in code generation and analysis, from identifying optimal improvements to exercising stronger judgment in refactoring decisions. It particularly excels at autonomous long-horizon coding tasks, where it can effectively plan and execute complex software projects spanning hours or days while maintaining consistent performance and reliability throughout the development cycle.
By using Claude Sonnet 4.5 in Amazon Bedrock, developers gain access to a fully managed service that not only provides a unified API for foundation models but ensures their data stays under complete control with enterprise-grade tools for security, and optimization.
Claude Sonnet 4.5 also seamlessly integrates with Amazon Bedrock AgentCore, enabling developers to maximize the model’s capabilities for building complex agents. AgentCore’s purpose-built infrastructure complements the model’s enhanced abilities in tool handling, memory management, and context understanding. Developers can leverage complete session isolation, 8-hour long-running support, and comprehensive observability features to deploy and monitor production-ready agents from autonomous security operations to complex enterprise workflows.
Business applications and use cases Beyond its technical capabilities, Sonnet 4.5 delivers practical business value through consistent performance and advanced problem-solving abilities. The model excels at producing and editing business documents while maintaining reliable performance across complex workflows.
The model demonstrates strength in several key industries:
Cybersecurity – Claude Sonnet 4.5 can be used to deploy agents that autonomously patch vulnerabilities before exploitation, shifting from reactive detection to proactive defense.
Finance – Sonnet 4.5 handles everything from entry-level financial analysis to advanced predictive analysis, helping transform manual audit preparation into intelligent risk management.
Research – Sonnet 4.5 can better handle tools, context, and deliver ready-to-go office files to drive expert analysis into final deliverables and actionable insights.
Sonnet 4.5 features in the Amazon Bedrock API Here are some highlights of Sonnet 4.5 in the Amazon Bedrock API:
Smart Context Window Management – The new API introduces intelligent handling when AI models reach their maximum capacity. Instead of returning errors when conversations get too long, Claude Sonnet 4.5 will now generate responses up to the available limit and clearly indicate why it stopped. This eliminates frustrating interruptions and allows users to maximize their available context window.
Tool Use Clearing for Efficiency – Claude Sonnet 4.5 enables automatic cleanup of tool interaction history during long conversations. When conversations involve multiple tool calls, the system can automatically remove older tool results while preserving recent ones. This keeps conversations efficient and prevents unnecessary token consumption, reducing costs while maintaining conversation quality.
Cross-Conversation Memory – A new memory capability enables Sonnet 4.5 to remember information across different conversations through the use of a local memory file. Users can explicitly ask the model to remember preferences, context, or important information that persists beyond a single chat session. This creates more personalized and contextually aware interactions while keeping the information safe within the local file.
With these new capabilities for managing context, developers can build AI agents capable of handling long-running tasks at higher intelligence without hitting context limits or losing critical information as frequently.
Getting started To begin working with Claude Sonnet 4.5, you can access it through Amazon Bedrock using the correct model ID. A good practice is to use the Amazon Bedrock Converse API to write code once and seamlessly switch between different models, making it easier to experiment with Sonnet 4.5 or any of the other models available in Amazon Bedrock.
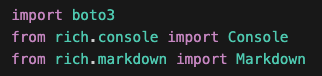
Let’s see this in action with a simple example. I’m going to use the Amazon Bedrock Converse API to send a prompt to Sonnet 4.5. I start by importing the modules I’m going to use. For this short example, I only need AWS SDK for Python (Boto3) so I can create a BedrockRuntimeClient. I’m also importing the rich package so I can format my output nicely later on.
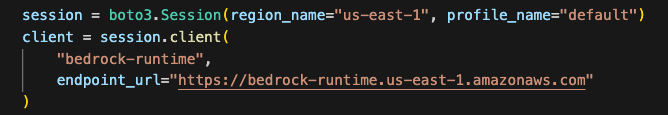
Following best practices, I create a boto3 session and create an Amazon Bedrock client from it instead of creating one directly. This gives you explicit control over configuration, improves thread safety, and makes your code more predictable and testable compared to relying on the default session.
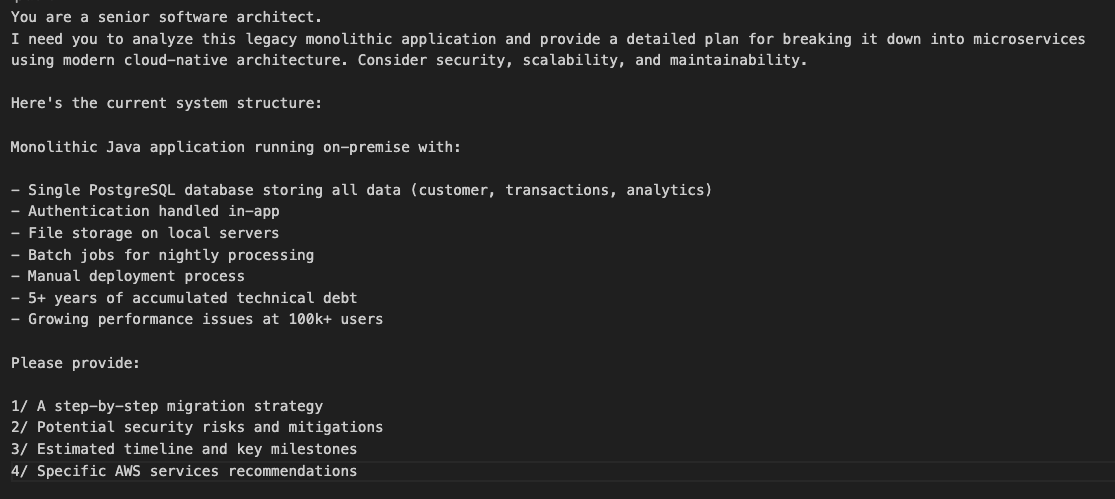
I want to give the model something with a bit of complexity instead of asking a simple question to demonstrate the power of Sonnet 4.5. So I’m going to give the model the current state of an imaginary legacy monolithic application written in Java with a single database and ask for a digital transformation plan which includes a migration strategy, risk assessment, estimated timeline and key milestones and specific AWS services recommendations.
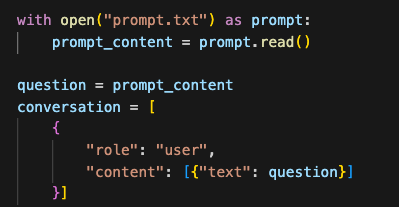
Because the prompt is quite long I put it in a text file locally and just load it up in code. I then set up the Amazon Bedrock converse payload setting the role to “user” to indicate that this is a message by the user of the application and add the prompt to the content.
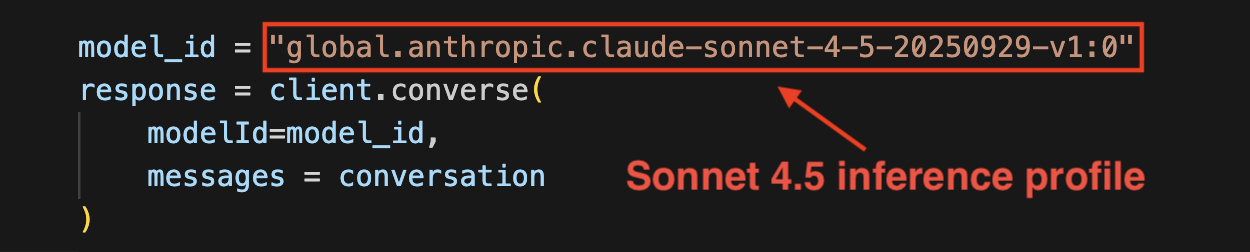
This is where the magic happens! We put it all together and call Claude Sonnet 4.5 using its model ID. Well, kind of. You can only access Sonnet 4.5 through an inference profile. This defines which AWS Regions will process your model requests and helps manage throughput and performance.
For this demo, I’ll be using one of Amazon Bedrock’s system-defined cross-Region inference profiles, which automatically routes requests across multiple Regions for optimal performance.
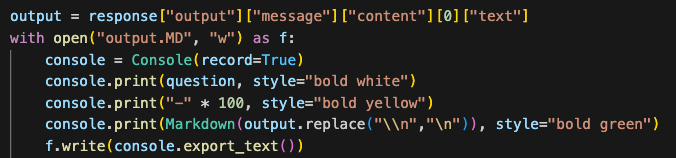
Now I just need to print to the screen to see the results. This is where I use the rich package I imported earlier just so we may have a nicely formatted output as I’m expecting a long response for this one. I also save the output to a file so I can have it handy as something to share with my teams.
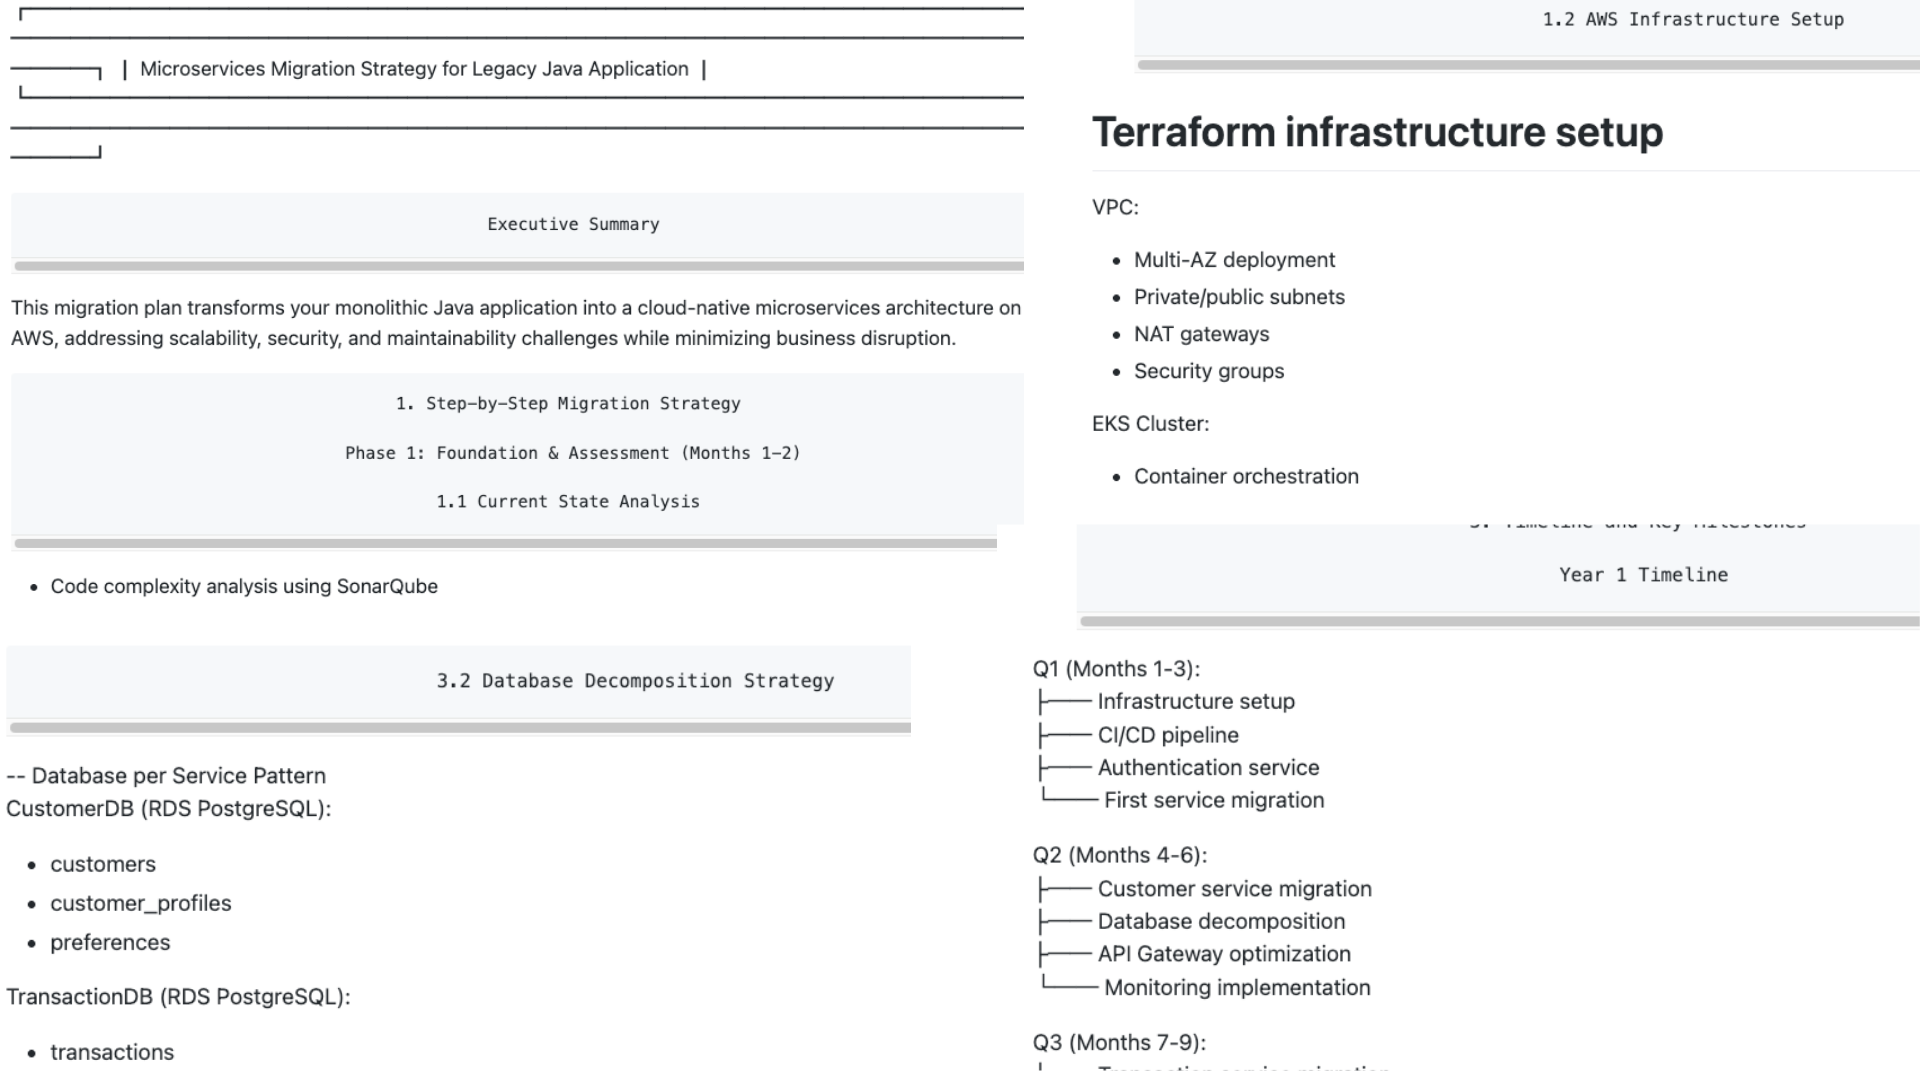
Ok, let’s check the results! As expected, Sonnet 4.5 worked through my requirements and provided extensive and deep guidance for my digital transformation plan that I could start putting into practice. It included an executive summary, a step-by-step migration strategy split into phases with time estimates, and even some code samples to seed the development process and start breaking things down into microservices. It also provided the business cases for introducing technology and recommended the correct AWS services for each scenario. Here are some highlights from the report.
Claude Sonnet 4.5 is able to maintain consistency while delivering creative solutions making it an ideal choice for businesses seeking to use AI for complex problem-solving and development tasks. Its enhanced capabilities in following directions and using tools effectively translate into more reliable and innovative solutions across various business contexts.
Things to know Claude Sonnet 4.5 represents a significant step forward in agent capabilities, particularly excelling in areas where consistent performance and creative problem-solving are essential. Its enhanced abilities in tool handling, memory management, and context processing make it particularly valuable across key industries such as finance, research, and cybersecurity. Whether handling complex development lifecycles, executing long-running tasks, or tackling business-critical workflows, Claude Sonnet 4.5 combines technical excellence with practical business value.
To learn more about Amazon Bedrock explore our self-paced Amazon Bedrock Workshop and discover how to use available models and their capabilities in your applications.
The
NixOS moderation team, which is theoretically
in charge of ensuring that community participation on the project’s
repositories and discussion forum remains welcoming and useful, has released
a joint resignation statement. This action was motivated by conflict with the project’s steering council (SC), which has repeatedly overridden the moderation team, leading the team members to decide that they could not continue acting as moderators. Arian Van Putten, speaking for the whole team, writes:
The SC has also shown, in private and public conversations, their lack of understanding of basic principles of community management and open communication. They have mistaken quiet and a lack of controversy for success and peace. They have consistently become upset when there is criticism, and gone quiet on crucial issues in between. We have some fundamental conflicts in this community, which absolutely require discussion. Meanwhile, discussion with the SC has only become less effective.
We think that the goal of moderation should not be to avoid difficult conversations – it’s to navigate those difficult conversations in ways that remain safe and constructive. We believe we’ve made considerable progress as a community on making those conversations happen, and we believe they need to happen more for the project to grow, not be suppressed. We thank everyone for the growth that we have seen, and for their efforts to avoid personal focus in discussion, especially recently.
The NixOS project has had problems with community moderation stretching back more than a year. With the next steering council election coming up soon, it will be interesting to see whether the community selects a council that feels differently or not.
Wow, can you all believe it? We’re nearing the end of the year already. Next thing you know, AWS re:Invent will be here! This is our biggest event that takes place every year in Las Vegas from December 1st to December 5th where we reveal and release many of the things that we’ve been working on. If you haven’t already, buy your tickets to AWS re:Invent 2025 to experience it in person. If you can’t make it to Vegas, don’t worry, make sure to stay tuned here on the AWS News Blog where will be covering many of the announcements as they happen.
However, there are plenty of new exciting new releases between now and then, so, as usual, let’s take a quick look at some of the highlights from last week so you can catch up on what’s been recently launched, starting with one of the most popular services: Amazon S3!
Last week was another S3 milestone with the addition of a preview in the AWS Console forAmazon S3 Tables. You can now take a quick peek at your S3 Tables right from the console, making it easier to understand their data structure and content without writing any SQL. This viewer-friendly feature is ready to use across all regions where S3 Tables are supported, with costs limited to just the S3 requests needed to display your table preview.
Other releases Here are some highlights from other services which also released some great stuff this week.
Amazon Bedrock AgentCore expands enterprise integration and automation options — Bedrock AgentCore services are leveling up their enterprise readiness with new support for Amazon VPC connectivity, AWS PrivateLink, AWS CloudFormation, and resource tagging, giving developers more control over security and infrastructure automation. These enhancements let you deploy AI agents that can securely access private resources, automate infrastructure deployment, and maintain organized resource management whether you’re using AgentCore Runtime for scalable agent deployment, Browser for web interactions, or Code Interpreter for secure code execution.
AWS X-Ray brings smart sampling for better error detection — AWS X-Ray now offers adaptive sampling that automatically adjusts trace capture rates within your defined limits, helping DevOps teams and SREs catch critical issues without oversampling during normal operations. The new capability includes Sampling Boost for increased sampling during anomalies and Anomaly Span Capture for targeted error tracing, giving teams better observability exactly when they need it while keeping costs in check.
AWS Clean Rooms enhances real-time collaboration wilth incremental ID mapping — AWS Clean Rooms now lets you update ID mapping tables with only new, modified, or deleted records through AWS Entity Resolution, making data synchronization across collaborators more efficient and timely. This improvement helps measurement providers maintain fresh datasets with advertisers and publishers while preserving privacy controls, enabling always-on campaign measurement without the need to reprocess entire datasets.
Short and sweet Here are some bite-sized updates that could prove really handy for your teams or workloads.
Keeping up with the latest EC2 instance types can be challenging. AWS Compute Optimizer now supports 99 additional instance types including the latest C8, M8, R8, and I8 families.
In competitive gaming, every millisecond counts! Amazon GameLift has launched a new Local Zone in Dallas bringing ultra-low latency game servers closer to players in Texas.
Don’t forget to check out all the upcoming AWS events happening across the globe. There are many exciting opportunities for you to attend free events where you can meet lots of people and learn a lot while enjoying a great day amongst other like-minded people in the tech industry.
And if you feel like competing for some cash, time is running out to be part of something extraordinary! The AWS AI Agent Global Hackathon continues until October 20, offering developers a unique opportunity to build innovative AI agents using AWS’s comprehensive gen AI stack. With over $45,000 in prizes and exclusive go-to-market opportunities up for grabs, don’t miss the chance to showcase your creativity and technical prowess in this global competition.
I hope you have found something useful or exciting within this last week’s launches. We post a weekly review every Monday to help you keep up with the latest from AWS so make sure to bookmark this and hopefully see you for the next one!
As with a mobile phone, a portable gaming device like the Steam Deck can contain
lots of personal information that the owner would like to keep
secret—especially given that such devices can do far more than gaming.
Alberto Garcia worked with his colleagues at Igalia and people at
Valve, the company behind the Steam gaming platform, to come
up with a new tool to manage encrypted filesystems for SteamOS, which is a Linux
distribution optimized for gaming. Garcia gave a talk about that tool, dirlock, at Open
Source Summit Europe, which was held in Amsterdam in late August.
In the talk, he looked at the design process for
the encrypted-files feature, the alternatives considered, and why they made
the choices
they did.
We recently upgraded the Maestro engine to go beyond scalability and improved its performance by 100X! The overall overhead is reduced from seconds to milliseconds. We have updated the Maestro open source project with this improvement! Please visit the Maestro GitHub repository to get started. If you find it useful, please give us a star.
Introduction
In our previous blog post, we introduced Maestro as a horizontally scalable workflow orchestrator designed to manage large-scale Data/ML workflows at Netflix. Over the past two and a half years, Maestro has achieved its design goal and successfully supported massive workflows with hundreds of thousands of jobs, managing millions of executions daily. As the adoption of Maestro increases at Netflix, new use cases have emerged, driven by Netflix’s evolving business needs, such as Live, Ads, and Games. To meet these needs, some of the workflows are now scheduled on a sub-hourly basis. Additionally, Maestro is increasingly being used for low-latency use cases, such as ad hoc queries, beyond traditional daily or hourly scheduled ETL data pipeline use cases.
While Maestro excels in orchestrating various heterogeneous workflows and managing user end-to-end development experiences, users have experienced noticeable speedbumps (i.e. ten seconds overhead) from the Maestro engine during workflow executions and development, affecting overall efficiency and productivity. Although being fully scalable to support Netflix-scale use cases, the processing overhead from Maestro internal engine state transitions and lifecycle activities have become a bottleneck, particularly during development cycles. Users have expressed the need for a high performance workflow engine to support iterative development use cases.
To visualize our end users’ needs for the workflow orchestrator, we create a 5-layer structure graph shown below. Before the change, Maestro reached level 4 but faced challenges to satisfy the user’s needs in level 5. With the new engine design, Maestro is able to power the users to work with their highest capacity and spark joy for end users during their development over the Maestro.
Figure 1. A 5-layer structure showing needs for the workflow orchestrator.
In this blog post, we will share our new engine details, explain our design trade-off decisions, and share learnings from this redesign work.
Architectural Evolution of Maestro
Before the change
To understand the improvements, we will first revisit the original architecture of Maestro to understand why the overhead is high. The system was divided into three main layers, as illustrated in the diagram below. In the sections that follow we will explain each layer and the role it played in our performance optimization.
Figure 2. The architecture diagram before the evolution.
Maestro API and Step Runtime Layer
This layer offers seamless integrations with other Netflix services (e.g., compute engines like Spark and Trino). Using Maestro, thousands of practitioners build production workflows using a paved path to access platform services . They can focus primarily on their business logic while relying on Maestro to manage the lifecycle of jobs and workflows plus the integration with data platform services and required integrations such as for authentication, monitoring and alerting. This layer functioned efficiently without introducing significant overhead.
Maestro Engine Layer
The Maestro engine serves several crucial functions:
Managing the lifecycle of workflows, their steps and maintaining their state machines
Supporting all user actions (e.g., start, restart, stop, pause) on workflow and step entities
Translating complex Maestro workflow graphs into parallel flows, where each flow is an array of sequentially chained flow tasks, translating every step into a flow task, and then executing transformed flows using the internal flow engine
Acting as a middle layer to maintain isolation between the Maestro step runtime layer and the underlying flow engine layer
Implementing required data access patterns and writing Maestro data into the database
In terms of speed, this layer had acceptable overhead but faced edge cases (e.g. a step might be concurrently executed by two workers at the same time, causing race conditions) due to lacking a strong guarantee from the internal flow engine and the external distributed job queue.
Maestro Internal Flow Engine Layer
The Maestro internal flow engine performed 2 primary functions:
Calling task’s execution functions at a given interval.
Starting the next tasks in an array of sequential task flows (not a graph), if applicable.
This foundational layer was based on Netflix OSS Conductor 2.x (deprecated since Apr 2021), which requires a dedicated set of separate database tables and distributed job queues.
The existing implementation of this layer introduces an impactful overhead (e.g. a few seconds to tens of seconds overall delays). The lack of strong guarantees (e.g. exactly once publishing) from this layer leads to race conditions which cause stuck jobs or lost executions.
Options to consider
We have evaluated three options to address those existing issues:
Option 1: Implement an internal flow engine optimized for Maestro specific use cases
Option 2: Upgrade Conductor library to 4.0, which addresses the overheads and offers other improvements and enhancements compared with Conductor 2.X.
Option 3: Use Temporal as the internal flow engine
One aspect that influenced our assessment of option two is that Conductor 2 provided a final callback capability in the state machine that was contributed specifically for Maestro’s use case to ensure database synchronization between the Conductor and Maestro engine states. It would require porting this functionality to Conductor 4 though it had been dropped given no other Conductor use cases besides Maestro relied on this. By rewriting the flow engine it would allow removal of several complex internal databases and database synchronization requirements which was attractive for simplifying operational reliability. Given Maestro did not need the full set of state engine features offered by Conductor, this motivated us to consider a flow engine rewrite as a higher priority.
The decision for Temporal was more straightforward. Temporal is optimized towards facilitating inter-process orchestration and would involve calling an external service to interact with the Temporal flow engine. Given Maestro is operating greater than a million tasks per day, many of which are long running, we felt it was an unnecessary source of risk to couple the DAG engine execution with an external service call. If our requirements went beyond lightweight state transition management we might reconsider because Temporal is a very robust control plane orchestration system, but for our needs it introduced complexity and potential reliability weak spots when there was no direct need for the advanced feature set that it offered.
After considering Option 2 and Option 3, we developed more conviction that Maestro’s architecture could be greatly simplified by not using a full DAG evaluation engine and having to maintain the state machine for two systems (Maestro and Conductor/Temporal). Therefore, we have decided to go with Option 1.
After the change
To address these issues, we completely rewrote the Maestro internal flow engine layer to satisfy Maestro’s specific needs and optimize its performance. This new flow engine is lightweight with minimal dependencies, focusing on excelling in the two primary functions mentioned above. We also replaced existing distributed job queues with internal ones to provide a strong guarantee.
The new engine is highly performant, efficient, scalable, and fault-tolerant. It is the foundation for all upper components of Maestro and provides the following guarantees to avoid race conditions:
A single step should only be executed by a single worker at any given time
Step state should never be rolled back
Steps should always eventually run to a terminal state
The internal flow state should be eventually consistent with the Maestro workflow state
External API and user actions should not cause race conditions on the workflow execution
Here is the new architecture diagram after the change, which is much simpler with less dependencies:
Figure 3. The architecture diagram after the evolution.
New Flow Engine Optimization
The new flow engine significantly boosts speed by maintaining state in memory. It ensures consistency by using Maestro engine’s database as the source of truth for workflow and step states. During bootstrapping, the flow engine rebuilds its in-memory state from the database, improving performance and simplifying the overall architecture. This is in contrast to the previous design in which multiple databases had to be reconciled against one another (Conductor’s tables and Maestro’s tables) or else suffer race conditions and rare orphaned job status.
The flow engine operates on in-memory flow states, resembling a write through caching pattern. Updates to workflow or step state in the database also update the in-memory flow state. If in-memory state is lost, the flow engine rebuilds it from the database, ensuring eventual consistency and resolving race conditions.
This design delivers lower latency and higher throughput, avoids inconsistencies from dual persistence, simplifies the architecture, and keeps the in‑memory view eventually consistent with the database.
Maintaining Scalability While Gaining Speed
With the new engine, we significantly boost performance by collocating flows and their tasks on the same node throughout their lifecycle. Therefore, states of a flow and its tasks will stay in a single node’s memory without persisting to the database. This stickiness and locality bring great performance benefits but inevitably impact scalability since tasks are no longer reassigned to a new worker of the whole cluster in each polling cycle.
To maintain horizontal scalability, we introduced a flow group concept to partition running flows into groups. In this way, each Maestro flow engine instance only needs to maintain ownership of groups rather than individual flows, reducing maintenance costs (e.g., heartbeat) and simplifying reconciliation by allowing each Maestro node to load flows for a group in batches. Each Maestro node claims ownership of a group of flows through a flow group actor and manages their entire lifecycle via child flow actors. If ownership is lost due to node failure or long JVM GC, another node can claim the group to resume flow executions by reconciling internal state from Maestro database. The following diagram illustrates the ownership maintenance.
Figure 4. Ownership maintenance sequence diagram.
Flow Partitioning
To efficiently distribute traffic, Maestro assigns a consistent group ID to flows/workflows by a simple stable ID assignment method, as shown in the diagram’s Partitioning Function box. We chose this simpler partitioning strategy over advanced ones, e.g. consistent hashing, primarily due to execution and reconciliation costs and consistency challenges in a distributed system.
Since Maestro decomposes workflows into hierarchical internal flows (e.g., foreach), parent flows need to interact with child flows across different groups. To enable this, the maximal group number from the parent, denoted as N’ in the diagram, is passed down to all child flows. This allows child flows, such as subworkflows or foreach iterations, to recompute their own group IDs and also ensures that a parent flow can always determine the group ID of its child flows using only their workflow identifiers.
Figure 5. Flow group partitioning mechanism diagram.
After a flow’s group ID is determined, the flow operator routes the flow request to the appropriate node. Each node owns a specific range of group IDs. For example, in the diagram, Node 1 owns groups 0, 1, and 2, while Node 3 owns groups 6, 7, and 8. The groups then contain the individual flows (e.g., Flow A, Flow B).
In this design, the group size is configurable and nodes can also have different group size configurations. The following diagram shows a flow group partitioning example while the maximal group number is changed during the engine execution without impacting any existing workflows.
Figure 6. A flow group partitioning example.
In short, Maestro flow engine shares the group info across the parent and child workflows to provide a flexible and stable partitioning mechanism to distribute work across the cluster.
Queue Optimization
We replaced both external distributed job queues in the existing system with internal ones, preserving the same fault‑tolerance and recovery guarantees while reducing latency and boosting throughput.
For the internal flow engine, the queue is a simple in‑memory Java blocking queue. It requires no persistence and can be rebuilt from Maestro state during reconciliation.
For the Maestro engine, we implemented a database‑backed in‑memory queue that provides exactly‑once publishing and at‑least‑once delivery guarantees, addressing multiple edge cases that previously required manual state correction.
This design is similar to the transactional outbox pattern. In the same transaction that updates Maestro tables, a row is inserted into the `maestro_queue` table. Upon transaction commit, the job is immediately pushed to a queue worker on the same node, eliminating polling latency. After successful processing, the worker deletes the row from the database. A periodic sweeper re-enqueues any rows whose timeout has expired, ensuring another worker picks them up if a worker stalls or a node fails.
This design handles failures cleanly. If the transaction fails, both data and message roll back atomically, no partial publishing. If a worker or node fails after commit, the timeout mechanism ensures the job is retried elsewhere. On restart, a node rebuilds its in‑memory queue from the queue table, providing at-least-once delivery guarantee.
To enhance scalability and avoid contention across event types, each event type is assigned a `queue_id`. Job messages are then partitioned by `queue_id`, optimizing performance and maintaining system efficiency under high load.
From Stateless Worker Model to Stateful Actor Model
Maestro previously used a shared-nothing stateless worker model with a polling mechanism. When a task started, its identifier was enqueued to a distributed task queue. A worker from the flow engine would pick the task identifier from the queue, load the complete states of the whole workflow (including the flow itself and every task), execute the task interface method once, write the updated task data back to the database, and put the task back in the queue with a polling delay. The worker would then forget this task and start polling the next one.
That architecture was simple and horizontally scalable (excluding database scalability considerations), but it had drawbacks. The process introduced considerable overhead due to polling intervals and state loading. The time spent in one polling cycle on distributed queues, loading complete states, and other DB queries was significant.
As Maestro engine decomposes complex workflow graphs into multiple flows, actions might involve multiple flows spanning multiple polling cycles, adding up to significant overhead (around ten seconds in the worst cases). Also, this design didn’t offer strong execution guarantees mainly because the distributed job queue could only provide at-least-once guarantees. Tasks might be dequeued and dispatched to multiple workers, workers might reset states in certain race conditions, or load stale states of other tasks and make incorrect decisions. For example, after a long garbage-collection pause or network hiccup, two workers can pick up the same task: one sets the task status as completed and then unblocks the downstream steps to move forward. However, the other worker, working off stale state, resets the task status back to running, leaving the whole workflow in a conflicting state.
In the new design, we developed a stateful actor model, keeping internal states in memory. All tasks of a workflow are collocated in the same Maestro node, providing the best performance as states are in the same JVM.
Actor-Based Model
The new flow engine fits well into an actor model. We also deliberately designed it to allow sharing certain local states (read-only) between parent, child, and sibling actors. This optimization gains performance benefits without losing thread safety due to Maestro’s use cases. We used Java 21’s virtual thread support to implement it with minimal dependencies.
The new actor-based flow engine is fully message/event-driven and can take actions immediately when events are received, eliminating polling interval delays. To maintain compatibility with the existing polling-based logic, we developed a wakeup mechanism. This model requires flow actors and their child task actors to be collocated in the same JVM for communication over the in-memory queue. Since the Maestro engine already decomposes large-scale workflow instances into many small flows, each flow has a limited number of tasks that fit well into memory.
Below is a high-level overview of the Maestro execution flow based on the actor model.
Figure 7. The high level overview of the Maestro execution.
When a workflow starts or during reconciliation, the flow engine inserts (if not existing) or loads the Maestro workflow and step instance from the database, transforming it into the internal flow and task state. This state remains in JVM memory until evicted (e.g., when the workflow instance reaches a terminal state).
A virtual thread is created for each entity (workflow instance or step attempt) as an actor to handle all updates or actions for this entity, ensuring thread safety and eliminating distributed locks and potential race conditions.
Each virtual thread actor contains an in-memory state, a thread-safe blocking queue, and a state machine to update states, ensuring thread safety and high efficiency.
Actors are organized hierarchically, with flow actors managing all their task actors. Flow actors and their task actors are kept in the same JVM for locality benefits, with the ability to relocate flow instances to other nodes if needed.
An event can wake up a virtual thread by pushing a message to the actor’s job queue, enabling Maestro to move toward an event-driven approach alongside the current polling-based approach.
A reconciliation process transforms the Maestro data model into the internal flow data.
Virtual Thread Based Implementation
We chose Java virtual threads to implement various actors (e.g. group actors and flow actors), which simplified the actor model implementation. With a smaller amount of code, we developed a fully functional and highly performant event-driven distributed flow engine. Virtual threads fit very well in use cases like state machine transitions within actors. They are lightweight enough to be created in a large number without Out-Of-Memory risks.
However, virtual threads can potentially deadlock. They’re not suitable for executing user-provided logic or complex step runtime logic that might depend on external libraries or services outside our control. To address this, we separate flow engine execution from task execution logic by adding a separate worker thread pool (not virtual threads) to run actual step runtime business logic like launching containers or making external API calls. Flow/task actors can wait indefinitely for the future of the thread poll executor to complete but don’t perform actual execution, allowing us to benefit from virtual threads while avoiding deadlock issues.
Figure 8. Virtual thread and worker thread separation.
Providing Strong Execution Guarantees
To provide strong execution guarantees, we implemented a generation ID-based solution to ensure that a single flow or task is executed by only one actor at any time, with states that never roll back and eventually reach a terminal state.
When a node claims a new group or a group with an expired heartbeat, it updates the database table row and increments the group generation ID. During node bootstrap, the group actor updates all its owned flows’ generation IDs while rebuilding internal flow states. When creating a new flow, the group actor verifies that the database generation ID matches its in-memory generation ID, otherwise rejecting the creation and reporting a retryable error to the caller. Please check the source code for the implementation details.
Figure 9. An example sequence diagram showing how generation id provides a strong guarantee.
Additionally, the new flow engine supports both event-driven execution and polling-based periodic reconciliation. Event-driven support allows us to extend polling intervals for state reconciliation at a very low cost, while polling-based reconciliation relaxes event delivery requirements to at-most-once.
Testing, Validation and Rollout
Migrating hundreds of thousands of Netflix data processing jobs to a new workflow engine required meticulous planning and execution to avoid data corruption, unexpected traffic patterns, and edge cases that could hinder performance gains. We adopted a principled approach to ensure a smooth transition:
Realistic Testing: Our testing mirrored real-world use cases as closely as possible.
Balanced Approach: We balanced the need for rapid delivery with comprehensive testing.
Minimal User Disruption: The goal was for users to be unaware of the underlying changes.
Clear Communication: For cases requiring user involvement, clear communication was provided.
Maestro Test Framework
To achieve our testing goals, we developed an adaptable testing framework for Maestro. This framework addresses the limitations of static unit and integration tests by providing a more dynamic and comprehensive approach, mimicking organic production traffic. It complements existing tests to instill confidence when rolling out major changes, such as new DAG engines.
The framework is designed to sample real user workflows, disconnecting business logic from external side effects like data reads or writes. This allows us to run workflow graphs of various shapes and sizes, reflecting the diverse use cases across Netflix. While system integrations are handled through deployment pipeline integration tests, the ability to exercise a wide variety of workflow topologies (e.g., parallel executions, for-each jobs, conditional branching and parameter passing between jobs) was crucial for ensuring the new flow engine’s correctness and performance.
The prototype workflow for the test framework focuses on auto-testing parameters, involving two main steps:
1. Caching Production Workflows:
Successful production instances are queried from a historical Maestro feed table over a specified period.
Run parameters, initiator, and instance IDs are extracted and organized into an instance data map.
YAML definitions and subworkflow IDs are pulled from S3 storage.
Both workflow definitions and instance data are cached on S3 for subsequent steps.
2. Pushing, Running, and Monitoring Workflows:
Cached workflow definitions and instance data are loaded.
Notebook-based jobs are replaced with custom notebooks, and certain job types (e.g., vanilla container runtime jobs, templated data movement jobs) and signal triggers are converted to a special no-op job type or skipped.
Abstract job types like Write-Audit-Publish are expressed as a single step template but are translated to multiple reified nodes of the DAG when executed. These are auto-translated into several custom notebook job types to replace the generated nodes.
Workflows and subworkflows are pushed, with only non-subworkflows being run using original production instance information.
1. In the parent workflow, each sub-workflow is replaced with a special no-op placeholder so that the overall topology is preserved but without executing any side-effects of child workflows and avoid cases using dynamic runtime parameter logic.
2. Each sub-workflow is then separately treated like a top-level parent workflow not initiated from its parent, to exercise the actual workflow steps of the sub-workflow.
The custom notebook internally compares all passed parameters for each job.
Workflow instances are monitored until termination (success or failure).
An email detailing failed workflow instances is generated.
Future phases of the test framework aim to expand support for native steps, more templates, Titus and Metaflow workflows, and include more robust signal testing. Further integration with the ecosystem, including dedicated Genie clusters for no-op jobs and DGS for our internal workflow UI feature verification, is also being explored.
Rollout Plan
Our rollout strategy prioritized minimal user disruption. We determined that an entire workflow, from its root instance, must reside in either the old or new flow engine, preventing mixed operations that could lead to complex failure modes and manual data reconciliation.
To facilitate this, we established a parallel infrastructure for the new workflow engine and leveraged our orchestrator gateway API to hide any routing or redirection logic from users. This approach provided excellent isolation for managing the migration. Initially, specific workflows could explicitly opt in via a system flag, allowing us to observe their execution and gain confidence. By scaling up traffic to the parallel infrastructure in direct proportion to what was scaled down from the original infrastructure, the dual infrastructure cost increase was negligible.
Once confident, we transitioned to a percentage-based cutover. In the event of a sustained failure in the new engine, our team could roll back a workflow by removing it from the new engine’s database and restarting it in the original stack. However, one consequence of rollback was that failed workflows had to restart from the beginning, recomputing previously successful steps, to ensure all artifacts were generated from a consistent flow engine.
Leveraging Maestro’s 10-day workflow timeout, we migrated users without disruption. Existing executions would either complete or time out. Upon restarting (due to failure/timeout) or triggering a new instance (due to success), the workflow would be picked up by the new engine. This effectively allowed us to gradually “drain” traffic from the old engine to the new one with no user involvement.
While the plan generally proceeded as expected with limited edge cases, we did encounter a few challenges:
Stuck Workflows: Around 50 workflows with defunct or incorrect ownership information entered a stuck state. In some cases, a backlog of queued instances behind a stuck instance created a race condition in which a new instance would be started immediately when an old instance was terminated, perpetually keeping the workflow on the old engine. For these, we proactively contacted users to negotiate manual stop-and-restart times, forcing them onto the new engine.
Configuration Discrepancies: A significant lesson learned was the importance of meticulous record-keeping and management of parallel infrastructure components. We discovered alerts, system flags, and feature flags configured for one stack but not the other. This led to a failure in a partner team’s system that dynamically rolled out a Python migration by analyzing workflow configurations. The absence of a required feature flag in the new engine stack caused the process to be silently skipped, resulting in incorrect Python version configurations for about 40 workflows. Although quickly remediated, this caused user inconvenience as affected workflows needed to be restarted and verified for no lingering data corruption issues. This issue also highlighted limitations in the testing framework since runtime configuration based on external API calls to the configuration service were not exercised in simulated workflow executions.
Despite these challenges, the migration was a success. We migrated over 60,000 active workflows generating over a million data processing tasks daily with almost no user involvement. By observing the flow engine’s lifecycle management latency, we validated a reduction in step launch overhead from around 5 seconds to 50 milliseconds. Workflow start overhead (incurred once per each workflow execution) also improved from 200 milliseconds to 50 milliseconds. Aggregating this over a million daily step executions translates to saving approximately 57 days of flow engine overhead per day, leading to a snappier user experience, more timely workflow status for data practitioners and greater overall task throughput for the same infrastructure scale.
We additionally realized significant benefits internally with reduced maintenance effort due to the new flow engine’s simplified set of database components. We were able to delete nearly 40TB of obsolete tables related to the previous stateless flow engine and saw a 90% reduction in internal database query traffic which had previously been a significant source of system alerts for the team.
Conclusion
The architectural evolution of Maestro represents a significant leap in performance, reducing overhead from seconds to milliseconds. This redesign with a stateful actor model not only enhances speed by 100X but also maintains scalability and reliability, ensuring Maestro continues to meet the diverse needs of Netflix’s data and ML workflows.
Key takeaways from this evolution include:
Performance matters: Even in a system designed for scale, the speed of individual operations significantly impacts user experience and productivity.
Simplicity wins: Reducing dependencies and simplifying architecture not only improved performance but also enhanced reliability and maintainability.
Strong guarantees are essential: Providing strong execution guarantees eliminates race conditions and edge cases that previously required manual intervention.
Locality optimizations pay off: Collocating related flows and tasks in the same JVM dramatically reduces overhead from the Maestro engine.
Modern language features help: Java 21’s virtual threads enabled an elegant actor-based implementation with minimal code complexity and dependencies.
We’re excited to share these improvements with the open-source community and look forward to seeing how Maestro continues to evolve. The performance gains we’ve achieved open new possibilities for low-latency workflow orchestration use cases while continuing to support the massive scale that Netflix and other organizations require.
Visit the Maestro GitHub repository to explore these improvements. If you have any questions, thoughts, or comments about Maestro, please feel free to create a GitHub issue in the Maestro repository. We are eager to hear from you. If you are passionate about solving large scale orchestration problems, please join us.
Acknowledgements
Special thanks to Big Data Orchestration team members for general contributions to Maestro and diligent review, discussion and incident response required to make this project successful: Davis Shepherd, Natallia Dzenisenka, Praneeth Yenugutala, Brittany Truong, Jonathan Indig, Deepak Ramalingam, Binbing Hou, Zhuoran Dong, Victor Dusa, and Gabriel Ikpaetuk — and and internal partners Yun Li and Romain Cledat.
Thank you to Anoop Panicker and Aravindan Ramkumar from our partner organization that leads Conductor development in Netflix. They helped us understand issues in Conductor 2.X that initially motivated the rearchitecture and helped provide context on later versions of Conductor that defined some of the core trade-offs for the decision to implement a custom DAG engine in Maestro.
We’d also like to thank our partners on the Data Security & Infrastructure and Engineering Support teams who helped identify and rapidly fix the configuration discrepancy error encountered during production rollout: Amer Hesson, Ye Ji, Sungmin Lee, Brandon Quan, Anmol Khurana, and Manav Garekar.
A special thanks also goes out to partners from the Data Experience team including Jeff Bothe, Justin Wei, and Andrew Seier. The flow engine speed improvement was actually so dramatic that it broke some integrations with our internal workflow UI that reported state transition durations. Our partners helped us catch and fix UI regressions before they shipped to avoid impact to users.
We also thank Prashanth Ramdas, Anjali Norwood, Eva Tse, Charles Zhao, Sumukh Shivaprakash, Joey Lynch, Harikrishna Menon, Marcelo Mayworm, Charles Smith and other leaders for their constructive feedback and guidance on the Maestro project.
Cloudflare launched fifteen years ago with a mission to help build a better Internet. Over that time the Internet has changed and so has what it needs from teams like ours. In this year’s Founder’s Letter, Matthew and Michelle discussed the role we have played in the evolution of the Internet, from helping encryption grow from 10% to 95% of Internet traffic to more recent challenges like how people consume content.
This year’s themes focused on helping prepare the Internet for a new model of monetization that encourages great content to be published, fostering more opportunities to build community both inside and outside of Cloudflare, and evergreen missions like making more features available to everyone and constantly improving the speed and security of what we offer.
We shipped a lot of new things this year. In case you missed the dozens of blog posts, here is a breakdown of everything we announced during Birthday Week 2025.
To support a diverse and open Internet, we are now sponsoring Ladybird (an independent browser) and Omarchy (an open-source Linux distribution and developer environment).
We are opening our office doors in four major cities (San Francisco, Austin, London, and Lisbon) as free hubs for startups to collaborate and connect with the builder community.
We are removing cost as a barrier for the next generation by giving students with .edu emails 12 months of free access to our paid developer platform features.
We are partnering with Coinbase to create the x402 Foundation, encouraging the adoption of the x402 protocol to allow clients and services to exchange value on the web using a common language
Our Automatic SSL/TLS system has upgraded over 6 million domains to more secure encryption modes by default and will soon automatically enable post-quantum connections.
We made our CSAM Scanning Tool easier to adopt by removing the need to create and provide unique credentials, helping more site owners protect their platforms.
Updates across Workers and beyond for a more powerful developer platform – such as support for larger and more concurrent Container images, support for external models from OpenAI and Anthropic in AI Search (previously AutoRAG), and more.
A deep-dive into how we’ve hardened the Workers runtime with new defense-in-depth security measures, including V8 sandboxes and hardware-assisted memory protection keys.
We announced the Cloudflare Email Service private beta, allowing developers to reliably send and receive transactional emails directly from Cloudflare Workers.
The TCP Connection Time (Trimean) graph shows that we are the fastest TCP connection time in 40% of measured ISPs – and the fastest across the top networks.
We are using our network’s vast performance data to tune congestion control algorithms, improving speeds by an average of 10% for QUIC traffic.
Come build with us!
Helping build a better Internet has always been about more than just technology. Like the announcements about interns or working together in our offices, the community of people behind helping build a better Internet matters to its future. This week, we rolled out our most ambitious set of initiatives ever to support the builders, founders, and students who are creating the future.
For founders and startups, we are thrilled to welcome Cohort #6 to the Workers Launchpad, our accelerator program that gives early-stage companies the resources they need to scale. But we’re not stopping there. We’re opening our doors, literally, by launching new physical hubs for startups in our San Francisco, Austin, London, and Lisbon offices. These spaces will provide access to mentorship, resources, and a community of fellow builders.
We’re also investing in the next generation of talent. We announced free access to the Cloudflare developer platform for all students, giving them the tools to learn and experiment without limits. To provide a path from the classroom to the industry, we also announced our goal to hire 1,111 interns in 2026 — our biggest commitment yet to fostering future tech leaders.
And because a better Internet is for everyone, we’re extending our support to non-profits and public-interest organizations, offering them free access to our production-grade developer tools, so they can focus on their missions.
Whether you’re a founder with a big idea, a student just getting started, or a team working for a cause you believe in, we want to help you succeed.
Until next year
Thank you to our customers, our community, and the millions of developers who trust us to help them build, secure, and accelerate the Internet. Your curiosity and feedback drive our innovation.
It’s been an incredible 15 years. And as always, we’re just getting started!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.