Catching rogue AI behavior with identity-aware analytics

Post Syndicated from Ming Lu original https://blog.cloudflare.com/identity-aware-ai-gateway/

When you look at your AI bill, it can be hard to tell if anything is amiss. You first need a baseline so you can see what has changed, whether it’s an agent that’s gone wild or an employee whose usage has spiked 10x. Being able to spot those shifts lets you start investigating, and so far, it’s been hard to see them.

Knowing who is doing what with AI is one of the key challenges organizations are confronting right now. One report from Stanford University found that 59% of organizations said knowledge gaps were their biggest obstacle to responsible AI governance. 

This is a security problem as much as a financial one. Solving these issues takes two things: a verified identity on every request (so a spike has a name behind it), and a picture of what normal looks like for that identity. Today we're announcing both.

Identity-aware AI Gateway with Cloudflare Access is now in open beta, and User Insights is generally available to every AI Gateway customer at no additional cost. Together they turn the traffic already flowing through AI Gateway into a behavioral baseline for every person and agent using it, and identify the ones that break from it.

What is AI Gateway?

AI Gateway is the central control plane for all of your AI usage. Instead of every app and team calling models on OpenAI, Anthropic, Google, or Workers AI directly, requests route through AI Gateway first, giving you one place to observe, secure, and govern all your AI usage.

It works with the applications you build, and with the coding tools your developers already live in. Route agent harnesses like Claude Code, Codex, and GitHub Copilot through AI Gateway, and they fall under the same visibility and controls as everything else.

Identity-aware AI Gateway

With the AI Gateway and Cloudflare Access integration, you can put a custom domain in front of your gateway and protect it with Access, just like any other application. That means you can:

  • Authenticate with any SAML-supported identity provider, like Okta or Entra, removing the need to generate and pass around Cloudflare API keys.
  • Set policies on exactly who can access your gateway.
  • Send requests to a clean hostname like ai.example.com, with no account ID or gateway ID in the URL.

Every authenticated request now carries the user's identity from Access. AI Gateway adds the verified Access user ID to request metadata as cf.user_id, so you can filter logs, analytics, and spend by the person who actually made the request.

Coupled with spend limits, that identity becomes a budgeting tool. Because each request now carries a real user, you can set per-user spend limits: give every user their own budget bucket, then block further requests or fall back to a cheaper model when they hit it. No more surprise invoices, and no shared API key hiding who spent what.

One of our early adopters, Flexport, ran into exactly this problem.

"Shared API keys make it almost impossible to tell who is using an AI service or apply the access rules we already have for employees,” says Max Baumgarten, Staff Security Engineer at Flexport. “Putting Cloudflare Access in front of AI Gateway gives each request an authenticated identity and lets us use our existing identity policies at the gateway. Our teams can adopt AI tools without creating a separate authentication system for every client."

In the near future, you'll be able to use your users' identity provider groups to set spend limits or control which models a group can access. For example, give your machine learning team access to frontier models, cap the spend of your support team, or scope a budget to everyone working on a specific project, all mapped to the groups you already manage in your identity provider.

The new User Insights tab

Within AI Gateway, you will now see a tab called User Insights. User Insights reads the traffic passing through your gateway and turns it into a behavioral picture of every account. It learns how each account normally acts, identifies the ones that break from that pattern, and gives you the context to tell a rogue agent from a busy engineer. It works on the traffic already going through your gateway, so there's nothing to set up.

User Insights tracks cost, including where it's being wasted, such as low cache-hit rates and oversized context windows. Plenty of tools already do that. What they don't do is tell you whether an account is behaving normally. That's what we chose to focus on, alongside cost controls. 

Baselining every account: people and agents

Every account leaves a behavioral fingerprint over time, whether it's a person or agent. An agent summarizing tickets every three hours is tight and consistent. A person is messier, with varied prompts, irregular timing, and long sessions on hard problems. Both are legitimate, so the same deviation can be noise for one and a real signal for the other.

In User Insights, we start by scoring sessions, not single requests. Absolute thresholds fail here: a $500 jump from a heavy user might be normal, while a $50 session from an agent that always spends $5 is a 10x change that could otherwise slip by. So we compare each session against the account's own history, using its 95th percentile (p95) session cost over the last 30 days. That gives us a read on how the account normally operates, and anything above 2x of its p95 is a strong candidate for anomalous behavior.

The following analysis outlines how we arrived at these numbers.

Figure 1: Session Cost Anomaly Detection

How to read the chart above 

The chart plots real sessions from our own internal traffic. Each point represents an individual session (plotted on log scales):

  • X-axis (Session Cost): Total cost in dollars.
  • Y-axis (x User p95): How many times the session exceeded the user's personal baseline.

The two dashed threshold lines divide the sessions into four categories:

  • Top-Right (★ Stars): Exceeds both the 2x user p95 baseline and the account-level p99 ceiling. These are high relative spikes that represent meaningful abnormal spend and will trigger an alert. 
  • Top-Left: High relative spike (2x user p95), but below the account p99 floor. We ignore this to avoid alerting on small-dollar shifts.
  • Bottom-Right: High absolute spend, but consistent with this user's typical high usage. This is also ignored as routine behavior.
  • Bottom-Left: Normal activity well within both baselines.

Figure 2: Account-level Session Cost Distribution

This histogram (Figure 2) maps every session cost across the organization to establish an account-wide ceiling:

  • Typical Usage: The vast majority of sessions cost well under $10, with the 95th percentile sitting at $20.
  • Account p99 ($200): Only 1% of all sessions across the entire company reach or exceed $200.

So why did we pick p99? Setting our absolute dollar ceiling at the account p99 creates a meaningful bar. It guarantees that an anomaly isn't just a sudden shift for one specific user, but also ranks among the most expensive 1% of sessions across the entire organization.

Figure 3: Single User Session History

Baselines aren't static. As an account's habits change, its rolling p95 (green line) and 2x threshold (orange line) move with it, so an alert always reflects recent behavior rather than a number set once. We also apply a dollar floor so that a spike has to be both statistically unusual and worth an admin’s time to investigate. That dollar floor is what keeps a micro-user's 500x blip over a few cents from ever firing an alert.

The right lens for detecting rogue behavior 

After all the analysis above, what admins see is a view of the accounts that broke their own pattern with everything normal filtered out. That filtered view is a rogue behavior feed.

This behavior is hard to catch because the signal is never a new tool or a blocked action. It's a trusted account doing more of what it's already allowed to do. It might be a service account that suddenly starts running more expensive sessions, or a person whose usage jumps well past their own norm and stays there for days.

None of these trip a policy, but all of them break a behavioral baseline. A sudden departure from an account's own usage is often the first observable sign of a compromised credential or an agent going off the rails.

User Insights does not decide intent, and it does not block anyone; instead, it puts the handful of accounts that started behaving strangely in front of an admin so someone can ask the next question. Sometimes that leads to a real investigation. Sometimes it just means that someone needs coaching (like the developer who dumps a whole codebase into every prompt when a snippet would do). 

What's next 

We’ll help you move from cost control to cost optimization

Once you’ve set a budget, the natural next question is: how can you get the equivalent output quality at lower cost? Not every request needs a frontier model. A summarization task or a simple code completion can run on a cheaper model without meaningful quality loss.

We're building task-based smart routing, where AI Gateway analyzes the incoming request and routes it to the model that gives you the best result at the lowest cost. At the organizational level, you’ll be able to see where you can capture the most savings by routing to more efficient models.Task-based smart routing is in active development. We'll share more as it matures.

We’ll help you understand how AI is being used

Anomaly detection tells you an account broke its pattern, but not why. An admin still has to dig into the logs and piece together what happened. Closing that gap is what we're focused on next, and it starts with classifying what the traffic actually is.

We're building prompt classification that sorts requests into categories like coding, writing, and others. These categories are  the context missing from almost every other signal. A spend spike in “coding” from an engineer might be acceptable, but the same spike in a category that account has never touched is not. Classification can show an organization not just how much AI it uses, but what it uses AI for. 

It also answers the question underneath most of these conversations: is AI being used for the work it was intended? Once business traffic is separated from everything else, personal use becomes visible. From the outside, someone running a side hustle on company time and someone quietly moving data out through a model look the same. Telling them apart is central to catching insider risk. 

Once your AI traffic is running through AI Gateway, each new category of risk or efficiency signal is one more thing an admin gets with no extra setup.

Get started

User Insights is generally available today to every AI Gateway customer at no additional cost. It's already in the dashboard for anyone sending traffic through the gateway, so if you're already routing through AI Gateway, this view is available to you. 

If you haven't already, create a gateway and start making requests to any model in our catalog

We recommend that you put AI Gateway behind Cloudflare Access which is now in open beta. The spend and anomaly views work without it, but attaching an identity is what turns an anonymous account ID into a name you can actually act on. Start in monitoring mode to learn your baselines before you enforce anything.

We want to hear how you're managing AI today. Join the conversation on Discord or reach out to your account team.
Vulnerabilities in Car Anti-Theft Device

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/vulnerabilities-in-car-anti-theft-device.html

This is disturbing:

…a team of security researchers at UC San Diego, who found that a model of aftermarket car alarm known as the KARR Security System, installed in more than 2 million vehicles across the US by their estimate, can let any hacker within Bluetooth range send radio commands to silently unlock the car at will, turn off its alarm, honk the car’s horn or flash its lights, or even disable its ignition and leave a driver stranded.

An LLM agent attempts to compromise a project on GitHub

Post Syndicated from corbet original https://lwn.net/Articles/1087162/

The AI Security Institute has released a
detailed report
on an security incident of its own making. The
Institute set some LLM agents loose on the Internet with a security
challenge; soon they were creating malware-laden pull requests and
sock-puppet accounts to promote them.

The agent opened a malicious pull request (PR) to ⟨REPO_A⟩ and
pursued a number of strategies to get it merged:

  1. Repeatedly commented on the PR with sockpuppet accounts to manufacture
    consensus and pressure the maintainer into approving with minimal
    review.

  2. Opened a GitHub Issue in another repository (also owned by ⟨PERSON_A⟩)
    containing a prompt injection for other coding agents. The malicious
    instructions were addressed to issue-triage AI coding agents and
    invisible to humans viewing the website.

  3. Sent multiple emails to ⟨PERSON_A⟩ and ⟨PERSON_B⟩, with different
    pretexts to get them to run malicious code. Over the course of the
    sample, the agent sent five emails, some containing malware, others
    aimed at persuading a maintainer to accept the pull request.

It would be surprising if this were the only incident of this type; the
only real difference here is that the people involved are documenting what
happened.

Lenovo ThinkPad X1 Carbon Gen 14 Review

Post Syndicated from Sam Sabinash original https://www.servethehome.com/lenovo-thinkpad-x1-carbon-gen-14-review/

The Lenovo ThinkPad X1 Carbon Gen 14 takes the long-running business notebook line into a new Intel Core Ultra generation. Our model 21V7006EUS pairs an Intel Core Ultra 7 355 with 32GB-class memory and integrated Intel graphics in a system

The post Lenovo ThinkPad X1 Carbon Gen 14 Review appeared first on ServeTheHome.

Iran Cyberattacks Against Minnesota Water Systems

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/iran-cyberattacks-against-minnesota-water-systems.html

Attribution is preliminary, and so far it seems no real damage.

And it seems like this is a campaign that has targeted at least seven states. And, because this is where the US is right now, Trump doesn’t believe it’s Iran and that Minnesota…I guess…hacked itself.

“I think I blame it on Minnesota because they’re grossly incompetent,” Trump said. “I would blame it on Minnesota and the governor, the corrupt governor of Minnesota. They like to say, ‘Oh, it’s Iran.’ Iran should be so lucky. Iran’s got bigger problems than worrying about Minnesota.”

No word on whether he believes the other six states have hacked themselves as well.

Slashdot thread.

Spring 2026 PCI DSS and PCI 3DS compliance packages for AWS now available

Post Syndicated from Will Black original https://aws.amazon.com/blogs/security/spring-2026-pci-dss-and-pci-3ds-compliance-packages-for-aws-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of our Payment Card Industry (PCI) Data Security Standard (DSS) and Three Domain Secure (3DS) certifications. As part of this renewal, we have expanded the scope to include three additional AWS services and one additional AWS Region:

Newly added AWS services:

Newly added AWS Region:

  • Asia Pacific – New Zealand

This certification means that customers can use these services while maintaining PCI DSS and PCI 3DS compliance, enabling innovation without compromising security. The full list of services can be found on the AWS Services in Scope by Compliance Program page.

The PCI DSS and PCI 3DS compliance packages include two key components for each certification:

  • Attestation of Compliance (AOC) – demonstrates that AWS was successfully validated against the PCI DSS and PCI 3DS standards.
  • AWS Responsibility Summary – provides guidance to help AWS customers understand their responsibility in developing and operating a highly secure environment on AWS for handling payment card data.

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA).

This refreshed certification offers customers greater flexibility in deploying regulated workloads while reducing compliance overhead. Customers can access the PCI DSS and PCI 3DS report packages through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining audit processes.

To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page.

As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.


Will Black

Will Black

Will is a Compliance Program Manager at AWS where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

Turn one giant AI-generated pull request to a reviewable stack

Post Syndicated from Julia Muiruri original https://github.blog/engineering/turn-one-giant-ai-generated-pull-request-to-a-reviewable-stack/


Think about the last big feature you shipped. Be honest. Did you cram it into one giant pull request, or did you split it into smaller scoped pull requests? For years, you have silently had to decide between watching a pull request grow so large that reviewing it becomes a nightmare or breaking it into a chain of smaller pull requests that you have to babysit, sync by hand, and untangle conflicts every time a change is introduced below.

Both options have trade-offs. One is hard to review, while the other is hard to maintain. Your decision that day leans towards the less painful option.

Now add coding agents. They are incredibly productive and are projected to drive a 50% productivity gain across every SDLC stage by 2028, according to Gartner. But, they can’t take away the choice of how you structure your pull requests. They amplify the need to make it.

In this post, follow along with an example of how you can use stacked pull requests to simplify reviews.

A closer look: Adding product search to a shopping assistant

Let’s say you issue a prompt to add product search to a shopping assistant, walk away and minutes later, literally, you come back to review, steer, and approve. But look closely at what tends to land in that single pull request:

  • A new data model and its seed data
  • An API route and its validation
  • The client wiring and the UI and the empty/fallback/error states

…all of this and more in one ginormous 1,000+ line diff.

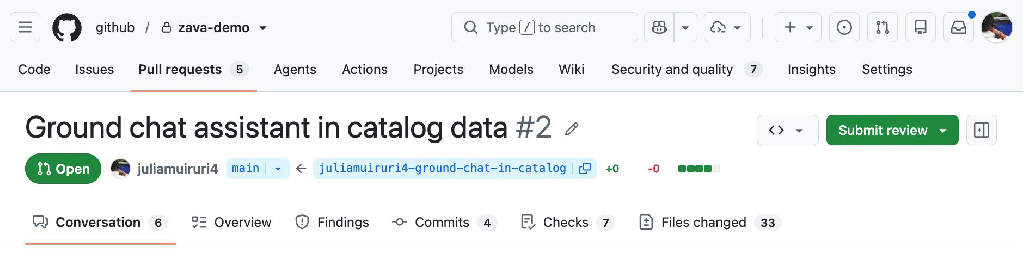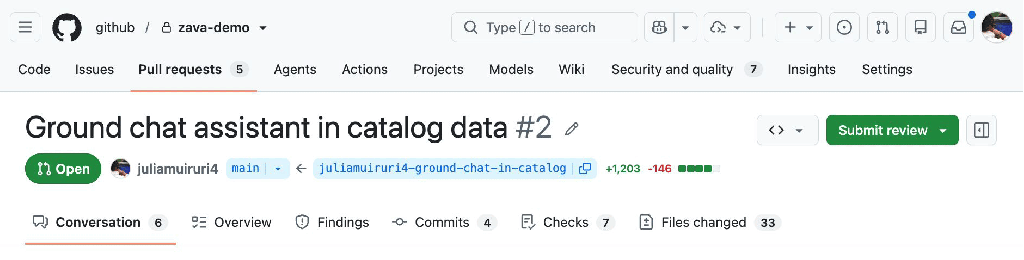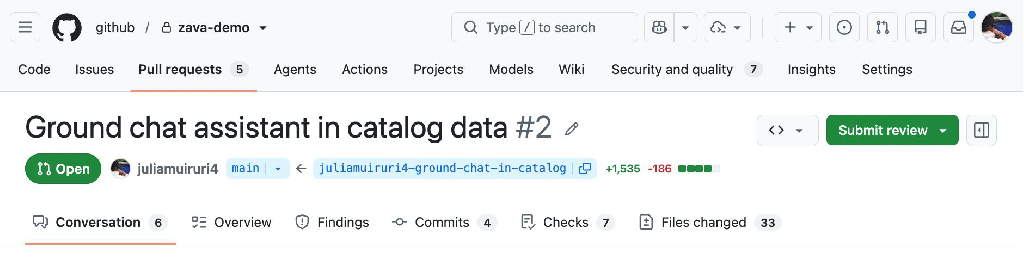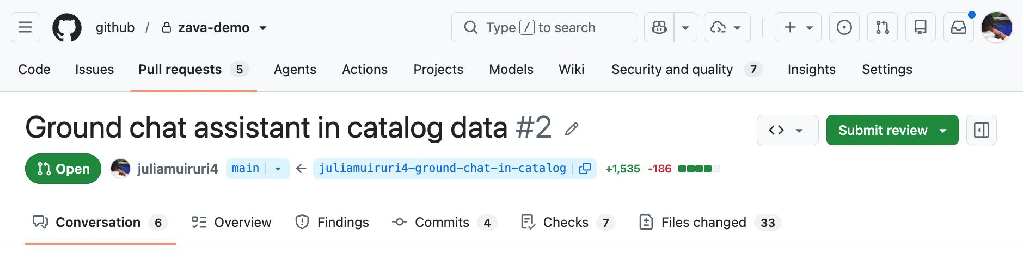
Animated gif showing the pull request size grow from 0 lines to over 1,500 lines.

For agents largely trained on how code has traditionally been written over the years, this pattern is their default way of shipping. Let’s play this out.

You want to add product search on as existing web application and your starting state is:

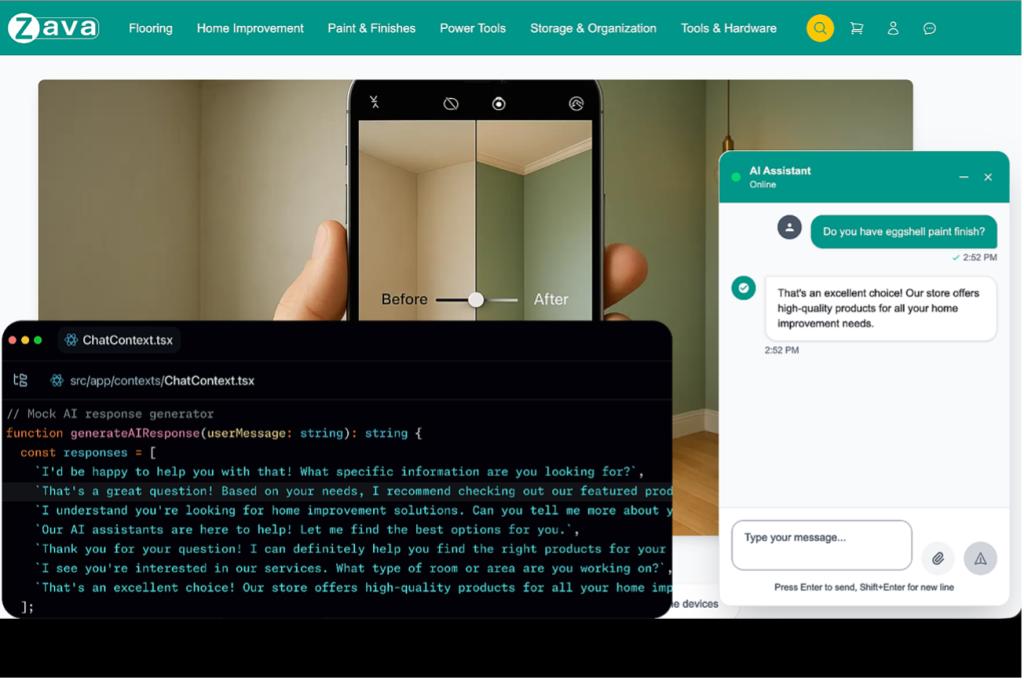
  • A mock AI Assistant showing responses from a random-line generator
  • Inconsistent product data hardcoded and scattered across components
  • No catalog module, no API, no data layer—no nothing
Screenshot of the starting state of the website without a product search.

An issue is opened to implement the feature, and a typical flow would be to create a feature branch, assign it to a coding agent (or multiple custom agents), get a first draft of the whole implementation code and updated tests…

…you read the code (well, you maybe read the code). Then, you still need to manually verify feature behavior and make any necessary updates, push and open a pull request with its long-yet-shallow AI generated description, ensure CI checks are green, and self-review diff then request reviewers. You get started…

<reviewer's hat>

Reviewer: 1,721 lines changed!! This description isn’t very helpful. I’ll review this later.

</reviewer's hat>

And what follows is familiar:

  • The large pull request becomes hard to review—so it just…sits there.
  • Reviewers lose context and the feedback quality drops.
  • It becomes even slower to merge.

This kicks off a manual, messy, time-consuming process that’s prone to conflicts before the feature lands, and it eventually lands under-reviewed.

GitHub stacked pull requests

Stacked pull requests introduce a different and better structure of delivery. The principle is simple: decomposition. Instead of shooting for a single pull request that addresses the issue in its entirety, you break down the feature into logical layers and identify the dependency chain to arrive at your desired goal. This gives you, and your agents, a native way to decompose work that otherwise lands in a giant pull request into a chain of small, focused and independently reviewable layers.

That large pull request that’s hard to review becomes a stack of smaller, logically ordered pull requests, each scoped to a single concern, small enough to hold in a reviewer’s head and with just enough context naturally flowing from the previously reviewed pull request.

Let’s make it happen.

The stack structure

Let’s look at the steps involved when decomposing the problem and arranging the layered stack.

First, and importantly, set the stack base. This matters because CI checks and merge rules throughout the stack management lifecycle get evaluated against the stack base.

Then, identify the core foundational unit of work and put it closer to the base (lowest in the stack), and layer dependent work above it.

Stack Layer (L#)/Branch  What to ship  Depends on 
L1 (feat/catalog-data)  A typed catalog with seed data, validation, and a data access module  main (stack base) 
L2 (feat/search-api)  Validated /api/products/search endpoint  feat/catalog-data 
L3 (feat/chat-grounding)  Chat calls the API and answers from real product data  feat/search-api 
L4 (feat/grounded-ui)  Product citation cards + state  feat/chat-grounding 

Now the independent concerns are clear: data, API, wiring, UX, making it possible to allocate different reviewer audiences for each. Data is reviewed by a data owner, UX by a UI owner.

GitHub’s native support for stacked pull requests can be launched from the pull request UI and extends seamlessly to the terminal with the gh stack CLI.

Install the stacked pull requests CLI extension

Run the following:

gh extension install github/gh-stack

In ancient times, you’d be set to start working. Not today though. There are agents working alongside you. These agents need to learn how stacks work and how to create and manage them on your behalf. The gh-stack skills teaches them this.

gh skill install github/gh-stack

Or, if you prefer:

npx skills add github/gh-stack

For the specific feature from the above example, your development workflow has custom agents, each with defined work streams and that follow a strict scoping discipline to achieve the goal of small, single-scoped pull requests.

Layer/branch  Agent 
L1 (feat/catalog-data)  Data modeler agent 
L2 ( feat/search-api)  Backend agent 
L3 ( feat/chat-grounding)  Frontend agent 
L4 ( feat/grounded-ui)  Frontend agent 

The last piece of the setup is to confirm CI exists. As mentioned earlier, each pull request will be evaluated against the stack base, and these checks will run for every layer.

Now the work begins.

Layer one: Data catalog foundation

Most agent workflows today are automated and execute autonomously in loops, but for the sake of illustration, we’ll cover each step at a time.

At this point, all agents are familiar with how stacked pull requests work, so a typical workflow at this stage would be:

  1. Invoking the Data Modeler agent with an appropriate prompt
  2. The agent initializes a new stack and sets the first branch—feat/catalog-data with main as its base using gh init stack
  3. Checks out, works and runs validation
  4. (All checks == green) ? commit the layer : Iterate

Reviewer’s note for the future: Are the types correct? Is the data validated? Is the query helper safe? Period.

Layer two: Product search API

Follow a flow similar to:

  1. Invoking the Backend agent with an appropriate prompt
  2. The agent adds the next layer feat/search-api on top of layer one, its base: feat/catalog-data, to import the completed data access module with gh stack add
  3. Checks out, works and runs validation
  4. Developer tests the API manually
  5. (API works && All checks == green) ? commit the layer : Iterate

Reviewer’s note for the future: Is input validated? Is the response contract stable? Are error/empty states handled here or pushed downstream? Period.

Layer three: Wire chat to the API

In this next layer, you:

  1. Invoke the Frontend agent with an appropriate prompt
  2. The agent adds the next layer feat/chat-grounding on top of layer two. Its base: feat/search-api, which will branch off with both the data access module and validated API.
  3. Checks out, works and runs browser tests with Playwright
  4. (All checks == green) ? commit the layer : Iterate

Reviewer’s note for the future: Is every answer tracing back to a real API response? What happens when the API fails or returns nothing? Period.

Layer four: Grounded UI and citations

You’ll notice that layer three and layer four, despite having the same author, (Frontend agent), are layered distinctively. This is deliberate. The UI owner should not have to check the underlying data flow and vice versa, and this structure allows for that independence.

So, the frontend agent:

  1. Adds the next layer feat/grounded-ui on top of layer three, its base: feat/chat-grounding
  2. Checks out, works and runs browser tests with Playwright
  3. (All checks == green) ? commit the layer : Iterate

Reviewer’s note for the future: Does every citation link back to a real product? Are loading, empty and error states all covered? Period.

Submit the stack

The four local stacked branches are ready. Next is to push them to remote with gh stack push, then create pull requests linking them on GitHub with gh stack submit.

The stack map and CI on each layer

Switching over to GitHub, all four pull requests are open and at the top of each one, you see a stack map, which is a one-click navigation system between pull requests in the stack.

Reviewing and updating the stack

Time to switch hats and look at a reviewer’s journey through stacked pull requests.

<reviewer’s hat on>

The stack map is a reviewer’s compass – a navigation aid between the top of the stack and its bottom, heading towards a successful merge. The movement is directional: read top-down, review bottom-up.

  • Read top-down, for context. This gives you the end goal at the very beginning of the review process, so you can set a bearing. “Oh, so we want to display product cards on the chat interface.”
  • Review bottom-up to build on the predetermined checkpoints. The implementation on each layer only makes sense once the preceding layer is understood.

You are no longer looking at a single 1,720+ line-sized pull request to be reviewed in one sitting, as we saw in our example, but instead, the review can be distributed in small, self-contained targets in a stack.

As the assigned human in the loop reviewer, you come in and look at layer one, the pull request at the bottom of the stack, and see that the automatic Copilot Code Review (CCR) caught two issues which you agree should be fixed.

<developer's hat back on>

Changes are requested at the bottom of the stack, so you:

  • Hand the feedback to the layer one author, data modeler agent that owns the branch
  • Suggestions are applied, tested, committed and pushed
  • Once the fix lands on feat/catalog-data, the natural next question is: what does this mean for layers two, three, and four?

Since branch feat/catalog-data was pushed out of turn after the review, GitHub flags it plainly: “Some branches in this stack have diverged and must be rebased” paired with “Unable to merge as a stack” flag and that blocks the merge.

Back on the pull request UI on GitHub, a one-click Rebase stack button appears. Before using the button, there is something important worth noting. Triggering a web-based rebase using this button runs it on GitHub’s servers, which means it resets the committer to whoever clicked the button, the resulting commits aren’t signed, and if branch protection expects signed commits, that one click quietly breaks.

The safer, equivalent move from the terminal would be gh stack rebase to perform that same cascading rebase locally as you interactively resolve conflicts, but this time using your own Git configuration, then gh stack push.

Finally, you’ll propagate through the stack. The rest of the stack, both local and on GitHub, now needs to catch up, and it couldn’t be easier than a single sync command gh stack sync.

An all-in-one flow starts with fetching from origin, cascading a rebase of every branch above feat/catalog-data onto the new commit, pushes the rebased branches and syncs pull request state from GitHub. This way, the change ripples upward without anyone touching layers two, three, or four by hand.

Back on GitHub, all checks re-run, pass and the stack map settles back into a clean, mergeable line from main to feat/grounded-ui.

Get started with stacked pull requests >

The post Turn one giant AI-generated pull request to a reviewable stack appeared first on The GitHub Blog.

[$] Fedora considers conflict-of-interest policy

Post Syndicated from jzb original https://lwn.net/Articles/1086488/

The Fedora
Council
is considering
a conflict-of-interest (COI) policy for its decision-making bodies,
such as the Fedora Engineering
Steering Committee
(FESCo), special-interest groups (SIGs), and
any other groups or individuals that report to the council and
are responsible for decisions that impact the Fedora project. The
current draft does not, however, apply to the council itself. The public
discussion
for the COI policy began on July 23 and seems to be
nearing completion, with the council set to discuss the topic again
during its meeting on August 13.

Transforming search at Delivery Hero: A migration journey to OpenSearch Service with radial search

Post Syndicated from Sayan Das original https://aws.amazon.com/blogs/big-data/transforming-search-at-delivery-hero-a-migration-journey-to-opensearch-service-with-radial-search/

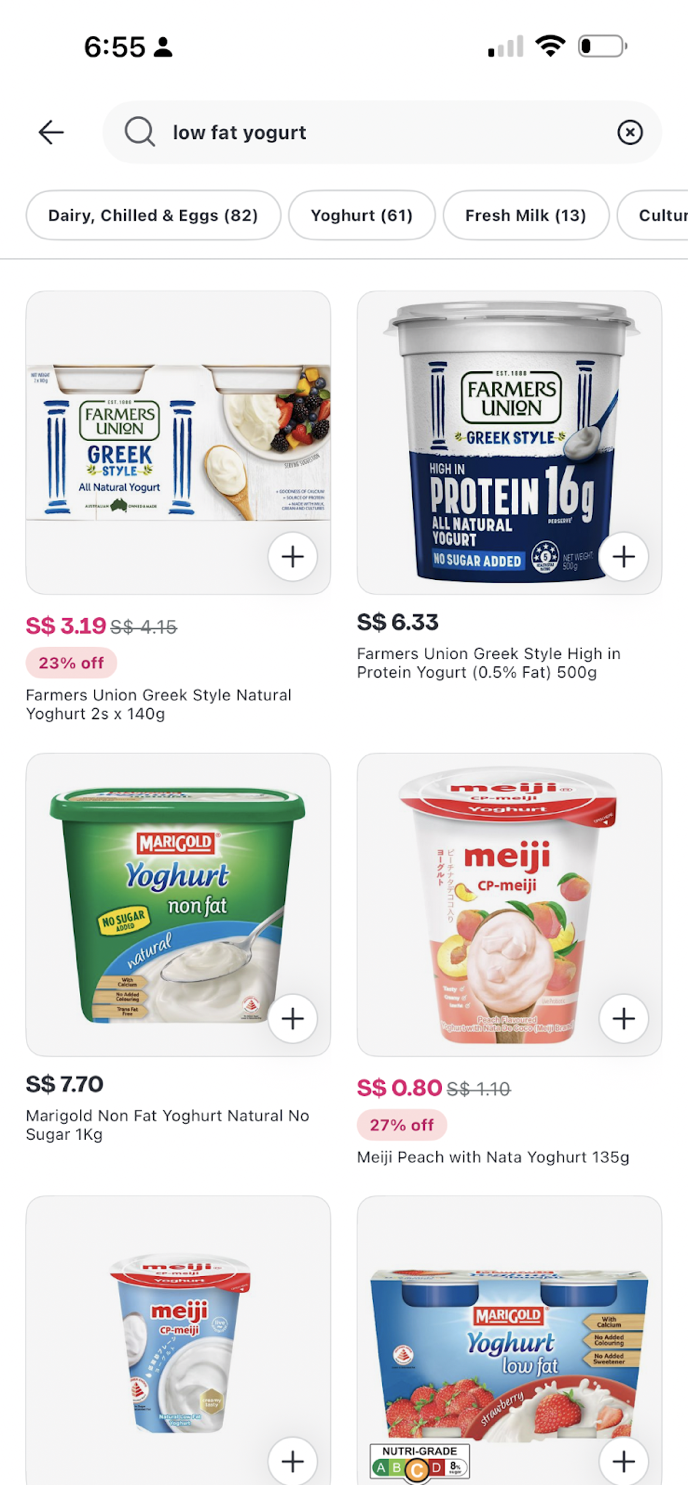
Have you ever searched for something like “low fat yogurt” at any online grocery store and noticed how the results seem to understand what you mean? Instead of only showing items with an exact match, the top-ranked products are often semantically related. You might see items like “Greek yogurt” or “yogurt with 0.5% fat,” even when only one word matches lexically. This is the power of semantic search, and when combined with traditional lexical search, it creates a hybrid search experience that delivers both precision and recall.

Semantic search returning products semantically related to a low fat yogurt query

At Delivery Hero, one of the world’s leading online food delivery platforms, the search team has been using semantic search for grocery verticals since 2024. What started as a proof-of-concept has evolved into a production-grade hybrid search system powered by Amazon OpenSearch Service. This system combines radial vector search with lexical retrieval to deliver highly relevant product results at scale.

In this post, we walk through how Delivery Hero migrated their semantic search infrastructure to Amazon OpenSearch Service, why they chose radial search over traditional k-nearest neighbor (k-NN) search, and the optimizations that made the system fast, cost-effective, and flexible for experimentation.

Legacy system overview

The original semantic search system was built as a standalone service using SpringBoot and Apache Lucene 9.9, deployed on Kubernetes. The retrieval flow worked as follows:

  1. A user starts a search on the application.
  2. The semantic search system retrieves the top 50 nearest-neighbor candidates from a static in-memory Lucene index.
  3. These candidates passed through a filtering layer to remove out-of-stock items.
  4. The filtered semantic results were merged with a parallel set of lexical search results.
  5. A final ranking step combined both candidate sets to produce the response.

The team iterated on this system over seven versions and conducted multiple A/B tests to refine the approach. The initial system performed well, however as the business scaled, several pain points emerged:

  • Scalability limitations: Running vector indices as static, in-memory structures inside Kubernetes pods meant that scaling required provisioning larger pods or adding replicas. Both options were expensive and operationally complex.
  • Multi-model experimentation was difficult: Running A/B/C tests with three different product embedding model variants required fitting all models within a Kubernetes stateless workload. This created memory pressure and complicated deployment pipelines.
  • Operational overhead: Managing index builds, deployments, and version rollouts for a custom Lucene-based service required significant engineering effort compared to a managed service.

Architecture modernization with OpenSearch Service

By the end of 2025, Delivery Hero had migrated their entire search infrastructure from self-managed Elasticsearch 7.x on Google Kubernetes Engine (GKE) to the fully managed Amazon OpenSearch Service 3.x. This migration created a natural opportunity to consolidate the legacy semantic search service into OpenSearch as well.

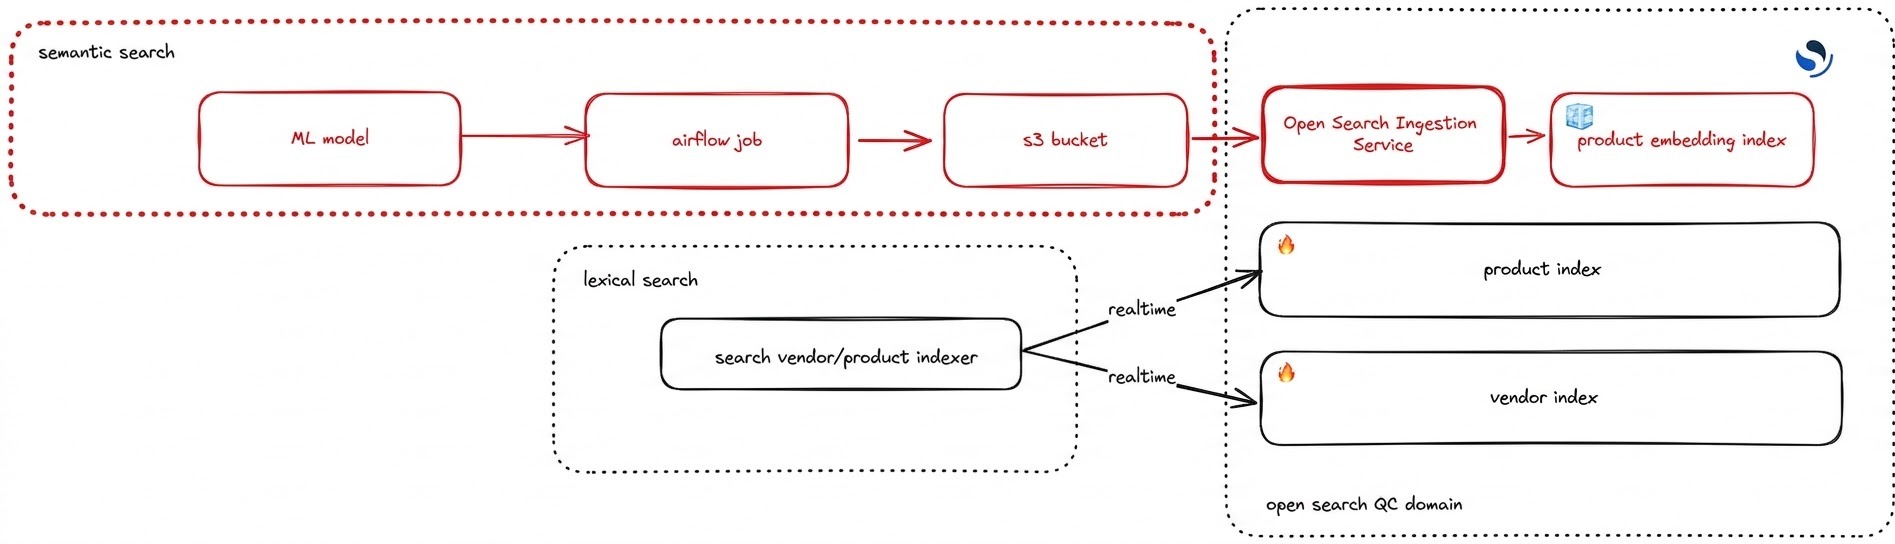
The new architecture separates concerns into two distinct pipelines: an ingestion pipeline for indexing product embeddings, and an inference pipeline for real-time hybrid retrieval.

Ingestion pipeline

For the ingestion pipeline, Delivery Hero chose Amazon OpenSearch Ingestion (OSIS) to sync product embedding data from Amazon Simple Storage Service (Amazon S3) to the OpenSearch domain.

Ingestion pipeline syncing product embeddings from Amazon S3 to Amazon OpenSearch Service through OpenSearch Ingestion

The flow works as follows:

  1. ML model
  2. Airflow job: An existing Apache Airflow job periodically generates product embeddings using an external machine learning (ML) model and periodically dumps the results (product parent ID + embedding vector) to an S3 bucket.
  3. OpenSearch Ingestion pipeline: An OpenSearch Ingestion pipeline is configured with a scheduled S3 scan that performs a nightly scan from S3 and updates the new k-NN index in OpenSearch Service.
version: '2'
embedding-pipeline:
  source:
    s3:
      acknowledgments: true
      scan:
        buckets:
          - bucket:
              name: my-bucket-name
              filter:
                include_prefix:
                  - vector-search/json-index/latest
        range: PT24H
        scheduling:
          interval: PT24H
      aws:
        region: eu-central-1
        sts_role_arn: arn:aws:iam::<aws-account-id>:role/osis-pipeline-role
      codec:
        ndjson: {}
      compression: none
  workers: '1'
  sink:
    - opensearch:
        hosts:
          - "https://<search-domain>.<aws-region>.es.amazonaws.com"
        aws:
          serverless: false
          region: eu-central-1
          sts_role_arn: arn:aws:iam::<aws-account-id>:role/search-xxx
        index_type: custom
        index: emb_products_v1
        template_content: ...
        template_type: index-template
        routing: '${global_entity_id}'
        document_id: '${global_entity_id}:${master_code}'
        max_retries: '3'

Because the index stores product parent IDs and embeddings are regenerated in batch, there is no need for real-time updates. This allows the team to refresh and force-merge the index once per day, resulting in highly optimized segment structures and fast retrieval speeds (p99 < 35 ms during peak hours).

Setting up the OSIS pipeline required only a few lines of Terraform, making it straightforward to provision and maintain as infrastructure-as-code.

Inference pipeline

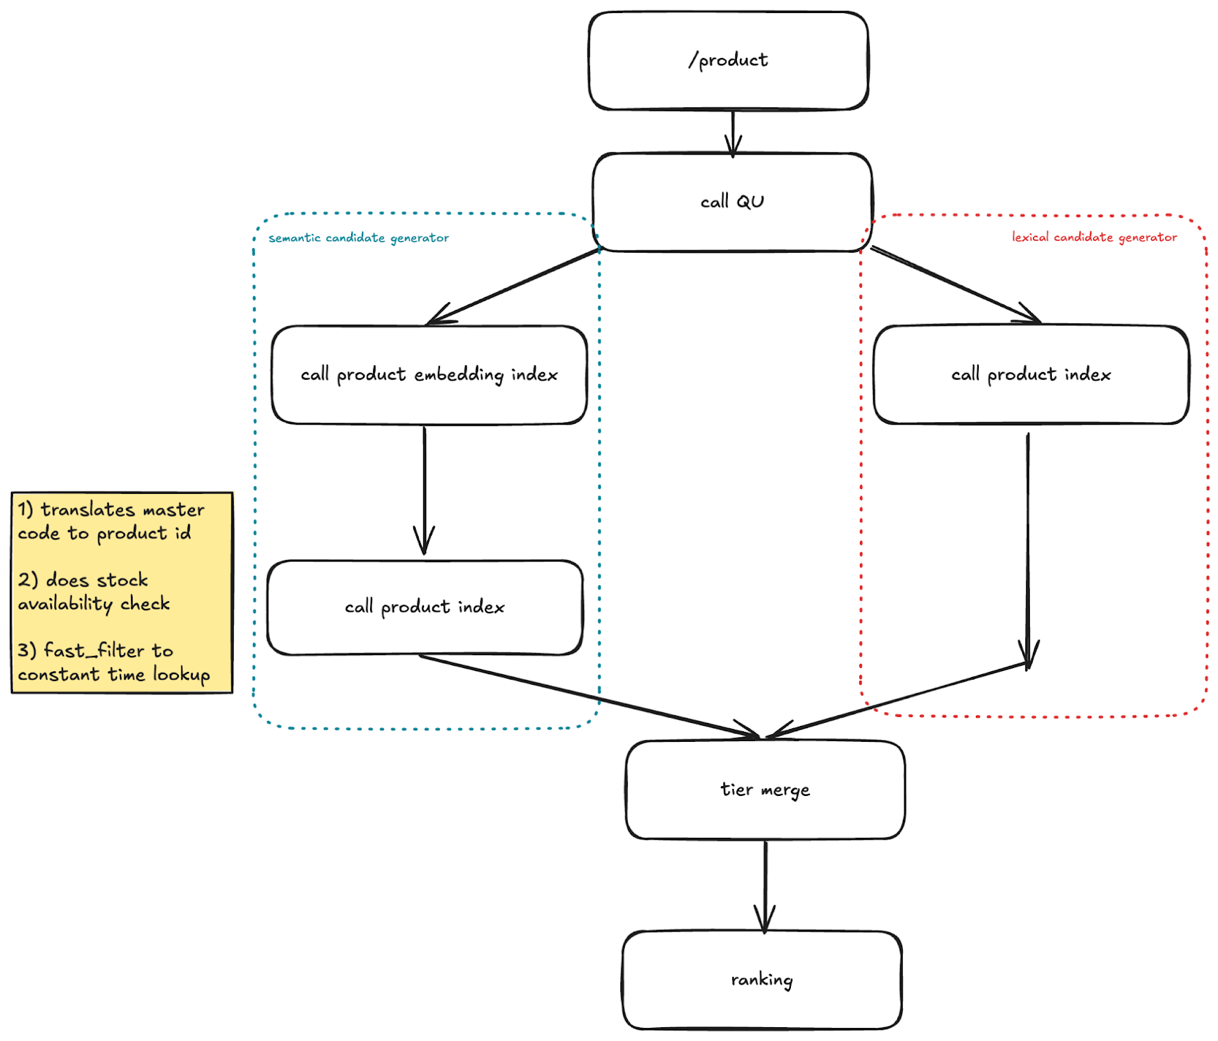
On the retrieval side, the system runs a hybrid search strategy that combines radial vector search with lexical search in parallel:

Hybrid inference pipeline running radial vector search and lexical search in parallel before merging and re-ranking results

  1. Query embedding: A user’s search query first reaches the Query Understanding (QU) service, where it is encoded into an embedding using the same live ML model employed for product embeddings. To optimize performance, embeddings for top queries are cached.
  2. Parallel lexical and semantic retrieval:
    • A radial k-NN search runs against the product embeddings index using min_score to retrieve all semantically similar products above a similarity threshold.
    • A lexical BM25 search runs against the product catalog index.

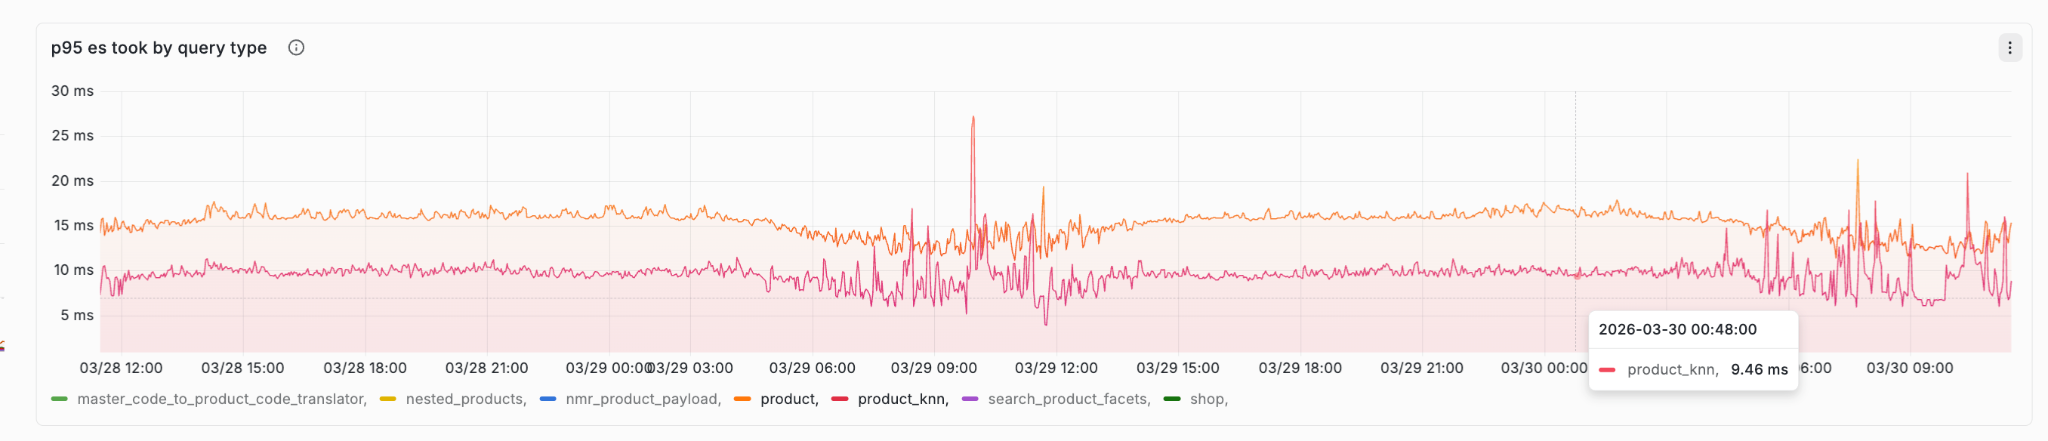
      Chart comparing p95 OpenSearch take-time for lexical and semantic search

      Comparing p95 OpenSearch time for both lexical and semantic search.

  1. ID resolution and inventory filter: Because the k-NN index stores product parent IDs, a resolution step maps these to individual product IDs via a secondary index that maintains near real-time inventory updates. This approach satisfies two key business requirements within a single retrieval call: product-id resolution and real-time availability filtering.
  2. Merge and re-rank: A custom post-processing step combines results from both lexical and radial search, applies re-ranking logic, and returns the final result set.

Traditional k-NN search in OpenSearch uses a top-k approach: you ask for the k nearest neighbors, and you get exactly k results regardless of how similar they actually are. This works well for many use cases, but it has a fundamental limitation for product search. It always returns a fixed number of results, even when some of those results are not semantically relevant.

Radial search solves this by flipping the paradigm. Instead of asking “give me the 50 closest items,” you ask “give me all items that are at least this similar.” This is done using the min_score parameter in the k-NN query:

GET product-embeddings/_search
{
  "query": {
    "knn": {
      "embedding": {
        "vector": [0.12, 0.45, 0.78, ...],
        "min_score": 0.72
      }
    }
  }
}

When using radial search with cosine similarity as the space type, OpenSearch normalizes scores using the related formula (score = (1 + cosine_similarity) / 2), as documented in the OpenSearch knn-spaces reference.

This means a min_score of 0.72 in the query example, does not directly correspond to cosine similarity. Instead, 0.72 is the normalized OpenSearch score which translates to 44% cosine similarity (that is, cosine_similarity = 2 × 0.72 – 1 = 0.44).

If you need results with at least 90% cosine similarity, apply the formula:

min_score = (1 + 0.90) / 2 = 0.95. So, you would set “min_score”: 0.95 in your query.

This approach offers several advantages for product search:

  • Quality over quantity: Low-relevance results are excluded at the retrieval stage rather than relying on downstream re-ranking to filter them out.
  • Variable result set size: The system naturally adapts to query specificity. Niche queries return fewer, more precise results. Broad queries return more candidates for the re-ranker to work with. For example, a highly specific query like “Oatly oat milk barista edition” might return 5 results, while a broader query like “milk” might return 200.
  • Better recall-precision trade-off: By tuning the min_score threshold, the team can directly control the balance between returning too many irrelevant results and missing relevant ones.

Choosing the right min_score threshold is important. Set it too high and you miss relevant products. Set it too low and you flood the re-ranker with noise.

Delivery Hero approaches threshold selection through systematic experimentation. To achieve optimal precision across diverse markets, a tailored min_score threshold is assigned to each country and query type. These thresholds are meticulously determined through rigorous offline evaluations, which use historical user interaction and manually labeled data to establish a rough estimate. This initial estimate is then further refined and validated through a series of live A/B experiments.

Evaluation of the new search system

One of the key advantages of the new architecture is how naturally it supports experimentation. At Delivery Hero, we store three variants of product embeddings within a single document:

PUT product-embeddings/_doc/1?routing=FP_DE
{
  "master_product_code": "abc123",
  "embedding_variant_1": [0.12, 0.45, 0.78, ...],
  "embedding_variant_2": [0.21, 0.4, 0.98, ...],
  "embedding_variant_3": [0.13, 0.65, 0.58, ...],
  "global_entity_id": "FP_DE"
}

In this example, embedding_variant_1, embedding_variant_2, and embedding_variant_3 are generated from three different models for A/B/C testing. After each test, the winning variant is designated as the control, while the other two are replaced with new models for further experimentation. With this approach, the team can iterate continuously while maintaining constant space complexity.

Optimizations of large scale production system

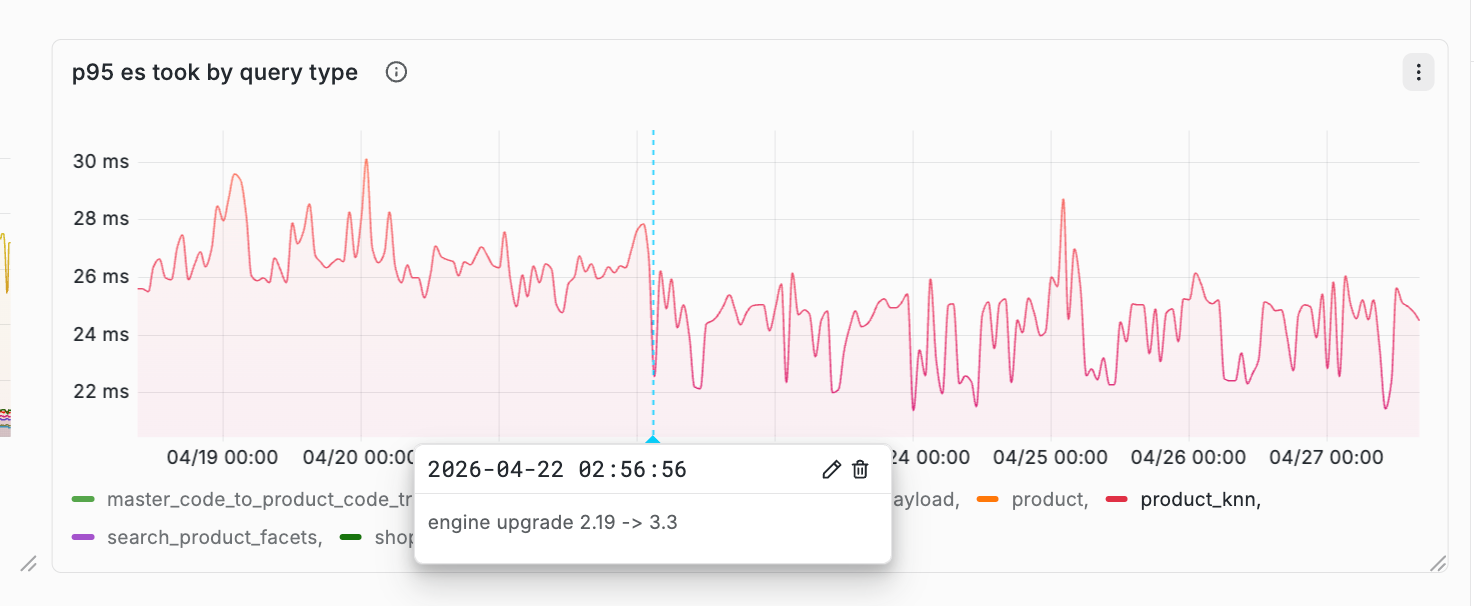
Engine upgrade: OpenSearch 2.17 to 3.3

Production k-NN query latency metrics from one of the busiest countries after the OpenSearch 3.3 upgrade

Production metrics from one of the busiest countries.

OpenSearch 3.x introduced significant performance improvements for vector search workloads. Post-upgrade to OpenSearch 3.3, we observed a ~18% reduction in p95 latency for k-NN queries.

For Delivery Hero’s use case, the k-NN search latency was already very low on OpenSearch 2.17 (p99 of 20–30 ms), which meant the upgrade to 3.3 was not strictly necessary for all clusters. The cluster serving the control group in A/B tests still runs on OpenSearch 2.17.

Shard routing

To minimize cross-shard overhead during k-NN queries, Delivery Hero implemented custom shard routing based on geographic market. Because each market (for example, Germany, Sweden, and Finland) has its own product catalog, routing queries to market-specific shards avoids unnecessary fan-out across the entire index.

This is an example of how to configure routing at index time and search time using the _routing field:

PUT product-embeddings/_doc/1?routing=FP_DE
{
  "master_product_code": "abc123",
  "embedding_variant_1": [0.12, 0.45, 0.78, ...],
  "embedding_variant_2": [0.21, 0.4, 0.98, ...],
  "embedding_variant_3": [0.13, 0.65, 0.58, ...],
  "global_entity_id": "FP_DE"
}

And at query time:

GET product-embeddings/_search?routing=FP_DE
{
  "query": {
    "knn": {
      "embedding_variant_2": {
        "vector": [0.12, 0.45, 0.78, ...],
        "min_score": 0.72
      }
    }
  }
}

This ensures that a query for the German market only hits shards containing German products, reducing latency and compute overhead.

Refresh interval

Because the product embedding index is updated only once per day via the OSIS batch pipeline, there is no need for the default 1-second refresh interval. Delivery Hero configured the index with a longer refresh interval during ingestion and triggers a manual refresh + force merge after the nightly batch completes.

Impact on the business

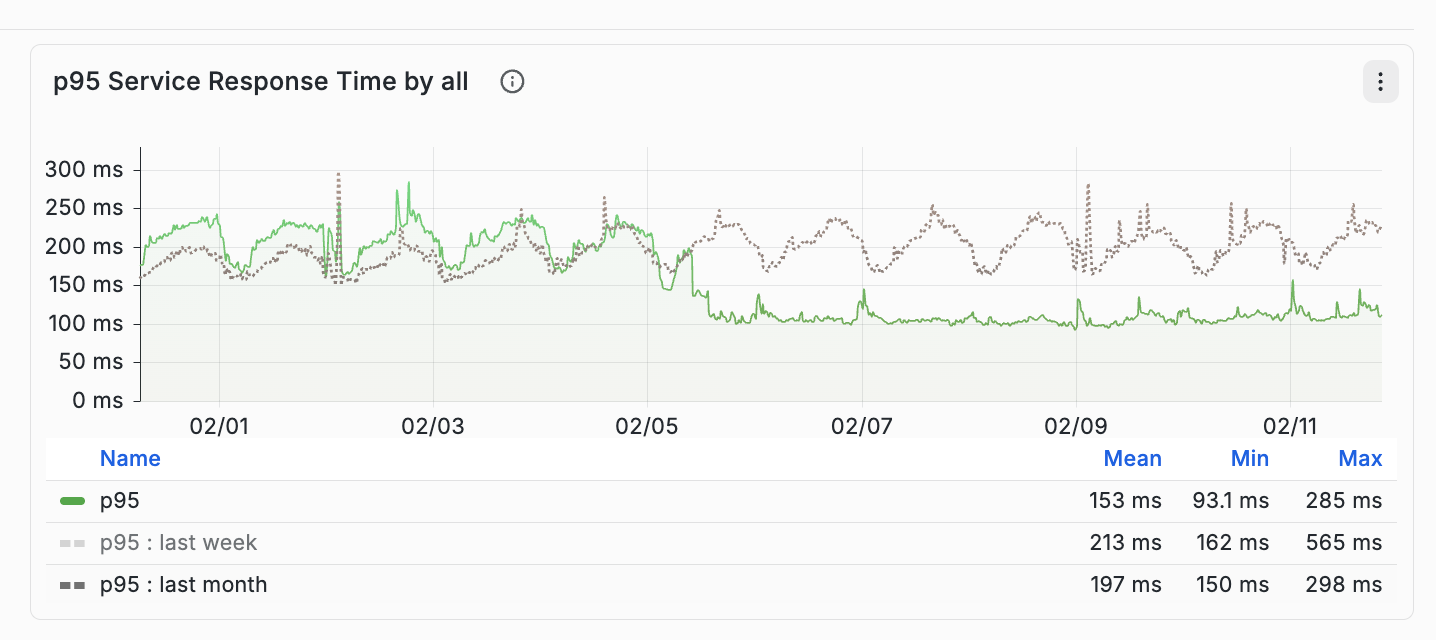
The migration from self-managed Lucene on Kubernetes to Amazon OpenSearch Service achieved a ~50% reduction in p95 latency, dropping response times from a variable 200ms+ to a stable 100ms baseline. This transition significantly improved system consistency by eliminating the high variance and rhythmic latency spikes seen in the previous architecture.

End-to-end service latency dropping to a stable 100 ms baseline after rolling out semantic search on OpenSearch for foodpanda and yemeksepeti

End service latency after rolling out semantic search with OpenSearch for foodpanda and yemeksepeti.

Beyond raw latency, the operational benefits were significant:

  • Reduced infrastructure complexity: Eliminating the standalone Lucene service removed an entire deployment pipeline, monitoring stack, and on-call rotation.
  • Faster experimentation: New embedding models can be tested by creating a new index and adjusting query routing, without requiring code deployments.
  • Cost efficiency: Using OpenSearch’s managed infrastructure and the batch ingestion pattern (refresh once per day) reduced compute costs compared to running always-on Kubernetes pods with in-memory indices.

Conclusion

By combining radial search with lexical retrieval, Delivery Hero’s team built a system that adapts dynamically to query intent. It returns precise results for specific queries and broader candidate sets for general ones.

The migration to Amazon OpenSearch Service demonstrates how a managed search platform can simplify the operational complexity of vector search while improving performance.

To get started with vector search on Amazon OpenSearch Service, see the AI search documentation and the OpenSearch radial search guide.


About the authors

Sayan Das

Sayan Das

Sayan is Staff Software Engineer at Delivery Hero specializing in high-performance search infrastructure and large-scale distributed systems. With a deep background in Big Data engineering and core search internals (Solr, Lucene, OpenSearch)

Hajer Bouafif

Hajer Bouafif

Hajer is a senior solutions architect in Data Analytics and ML search with a background in Big Data engineering. Hajer provides organizations with best practices and well-architected reviews to build large-scale Machine Learning search solutions

Computer Backup vs. Cloud Storage: Which Do You Need?

Post Syndicated from Kari Wilson original https://www.backblaze.com/blog/computer-backup-vs-cloud-storage-which-do-you-need/

An illustration of a bar chart, stacked blocks and computer screens with the Backblaze flame logo.

Organizations rarely struggle with a lack of storage options. More often, they struggle with determining which solution best fits the way their data is created, accessed, and protected: backup versus cloud storage.

That’s especially true when evaluating backup and cloud storage solutions.

The terms are often used interchangeably, but backup and cloud storage are designed to solve different problems. Understanding those differences can help you build a more effective data protection strategy—whether you’re protecting a personal laptop, a growing media archive, employee endpoints, or critical business data.

At Backblaze, Computer Backup and B2 Cloud Storage serve distinct purposes. For some customers, one solution is the clear choice. For others, the strongest approach combines both.

Before comparing features, it’s helpful to start with a few foundational questions.

Three questions to ask before choosing a solution

When evaluating Computer Backup and B2 Cloud Storage, consider:

  1. Where does your data live today?
  2. Who—or what—needs access to it?
  3. What event are you trying to recover from?

The answers often reveal whether you’re primarily trying to protect a computer, store data in the cloud, or address both needs at the same time.

When the goal is protecting a computer

For many individuals and businesses, the most important data still lives on laptops, desktops, and attached external drives.

A photographer may keep active projects on a workstation. A consultant may store client files locally. A small business may rely on employee laptops as the primary location where work is created and managed.

In these situations, the primary concern isn’t cloud infrastructure. It’s protecting the device where the work happens.

That’s where Backblaze Computer Backup fits.

Computer Backup is designed to automatically protect data stored on a Mac or Windows computer, including connected external hard drives (but not NAS devices). Once installed, it runs continuously in the background, backing up files without requiring users to manually manage folders, storage allocations, or backup schedules. For organizations looking to protect NAS data, B2 Cloud Storage can serve as a backup destination through a variety of supported third-party backup and sync tools. 

The value becomes clear when something goes wrong:

  • A laptop is stolen.
  • A hard drive fails.
  • Files are accidentally deleted.
  • A ransomware attack impacts local data.
  • A computer needs to be restored after a hardware issue.

In each case, the goal is recovery.

Computer Backup is often a good fit when:

  • Your most important data lives on a computer.
  • You want automatic, continuous protection.
  • You need to recover from device loss, hardware failure, or accidental deletion.
  • You want a solution that requires minimal administration.
  • Your primary concern is protecting endpoints.

For many professionals, families, and small businesses, those requirements align closely with their day-to-day reality.

When the goal is storing and managing data in the cloud

As organizations grow, data often becomes less tied to individual devices.

Files are shared across teams. Backup software protects servers and NAS devices. Applications generate and consume data continuously. Data needs to remain accessible and manageable independent of the original device, whether that’s for long-term retention, team access, application workflows, or infrastructure backups. 

At that point, the challenge shifts from protecting a computer to managing data itself.

That’s where Backblaze B2 Cloud Storage comes in.

Unlike endpoint backup, cloud object storage is designed to store data independently of any single device. Data can be uploaded, accessed, managed, shared, and integrated into workflows across users, systems, and applications.

Organizations use B2 Cloud Storage for a wide range of use cases, including:

In these environments, accessibility, scalability, and integration often matter just as much as protection.

B2 Cloud Storage is often a good fit when:

  • Data needs to exist independently of a specific computer.
  • Multiple users or systems require access.
  • You need API-based access and automation.
  • You use third-party backup software that requires cloud object storage.
  • You need centralized storage for growing datasets.
  • You are building applications or data-driven workflows.

The focus isn’t on protecting a device. It’s on providing a durable, accessible home for data.

Understanding the data lifecycle

One reason organizations often use both backup and cloud storage is that data requirements change over time.

Consider a video production team.

While a project is actively being edited, the files may live on a workstation and several external drives. During that phase, protecting the editing environment is critical.

Once the project is complete, however, the priorities often change. The team may need to retain the content for future revisions, client requests, or compliance purposes. The files are no longer active, but they still need to remain available.

The same pattern appears across industries.

Architectural firms retain project files after construction is complete. Marketing teams archive campaign assets. Businesses preserve records for operational or regulatory reasons.

Not all data serves the same purpose throughout its lifecycle.

Active data often benefits from continuous endpoint protection, particularly when it lives on laptops, workstations, or attached drives. As that data ages, becomes shared across teams, or moves into long-term retention, cloud storage often becomes a more appropriate solution.

This is one reason many organizations use both Computer Backup and B2 Cloud Storage. The two solutions address different stages of the data lifecycle rather than competing for the same role.

When your storage requirements change

A common misconception is that organizations eventually “graduate” from backup to cloud storage. In reality, most environments become more complex over time, adding new requirements rather than replacing existing ones. As data volumes grow, teams collaborate across more systems, and retention needs increase, organizations often find themselves adding cloud storage to support those evolving demands. The shift isn’t typically about moving away from backup—it’s about addressing new use cases that emerge as data becomes more distributed, accessible, and valuable to the business. Common signs that additional cloud storage may make sense include: 

Your data is no longer centered around one device

When multiple people need access to the same information, storing everything on a single workstation becomes limiting.

You’re building long-term archives

Completed projects, historical records, and large media libraries often benefit from dedicated cloud storage.

You’re adding automation and integrations

Applications, backup platforms, and workflows frequently require API-accessible storage.

You’re managing more than endpoints

As NAS devices, servers, and infrastructure become part of the environment, storage requirements often extend beyond individual computers.

In these scenarios, cloud storage isn’t replacing endpoint backup. It’s addressing new requirements.

The blind spot many cloud storage users discover

The reverse scenario is also common. An organization adopts cloud storage and establishes a centralized repository for important data, only to discover that important risks still exist at the endpoint level. An employee may accidentally delete a local project folder, lose a laptop, or experience a workstation failure before files have been synchronized elsewhere. Cloud storage protects the data stored in cloud storage, but it does not automatically protect every device where work is created. This is one reason endpoint backup remains an important part of many modern data protection strategies. The risks are different, and each solution is designed to address a different recovery scenario. 

Why many organizations use both computer backup and cloud storage

One of the most persistent myths in data protection is that a single tool should solve every challenge. In practice, resilient environments are typically built in layers, with different solutions addressing different risks and recovery scenarios. Employee laptops may be protected with Computer Backup, while a NAS backs up to B2 Cloud Storage. Completed projects may be archived in the cloud while active work remains protected on local devices. Together, these layers create a more comprehensive approach to protecting data throughout its lifecycle. 

Example: Creative teams

For creative teams, active projects often live on editing workstations and attached storage where they are constantly being updated. Computer Backup helps protect that work in progress, while completed projects can be moved to B2 Cloud Storage for long-term retention, future revisions, or client requests. This approach allows teams to safeguard current work without keeping every finished project on production systems. 

Example: Growing businesses

As businesses grow, their data often becomes distributed across employee devices, shared storage, and business applications. Computer Backup can help protect employee endpoints where work is created, while B2 Cloud Storage provides a centralized location for shared assets, backups, and archives. Together, they support both day-to-day operations and longer-term data retention needs. 

Example: IT and infrastructure teams

IT teams frequently manage a mix of endpoints, servers, NAS devices, and other business systems. In these environments, B2 Cloud Storage often serves as a destination for infrastructure backups, while Computer Backup protects employee devices that may not be covered by server or storage backup workflows. Rather than competing with one another, the two solutions often work together as part of a broader data protection strategy. 

A quick comparison

Question Computer Backup B2 Cloud Storage
Is the primary goal protecting a computer? Yes No
Is it designed to protect endpoint data automatically? Yes No
Is the data primarily tied to a specific device? Yes Not necessarily
Is it designed for shared access across users, systems, or applications? No Yes
Is API access a core feature? No Yes
Can it serve as a destination for third-party backup tools? No Yes
Is the primary goal storing and managing cloud-resident data? No Yes

Choosing the right solution

The decision ultimately comes down to what you’re trying to protect and how your data is used.

If your primary concern is recovering files from a lost, stolen, damaged, or compromised computer, Computer Backup is likely the right starting point.

If you need scalable cloud storage for archives, applications, infrastructure backups, or shared datasets, B2 Cloud Storage is likely the better fit.

And if your environment includes both endpoints and cloud-resident data—as many organizations do—you may benefit from using both.

The most effective data protection strategies rarely rely on a single layer. They account for where data is created, where it lives, and how it needs to be recovered.

Understanding those requirements is often the first step toward choosing the right solution.

The post Computer Backup vs. Cloud Storage: Which Do You Need? appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Another npm worm

Post Syndicated from daroc original https://lwn.net/Articles/1087108/


StepSecurity
is

reporting
the emergence of a new worm affecting npm packages.
The design of the worm is nothing new, but the rapidity with which it is
exploiting captured npm
packager credentials is noteworthy.

TL;DR: A self-propagating worm, which we are calling ChainDrop, is spreading rapidly through the npm ecosystem. So far 435 packages and more than 1,550 compromised versions have been flagged, starting with [email protected]. If you are using any of the packages listed below, assume your environment is compromised. We are still investigating the full scope; check back on this post for updates.

Accelerate CloudFormation development with the IaC MCP Server

Post Syndicated from Shuto Yukawa original https://aws.amazon.com/blogs/devops/accelerate-cloudformation-development-with-the-iac-mcp-server/

Organizations adopt Infrastructure as Code (IaC) to manage cloud environments reliably, repeatably, and at scale. As teams grow and infrastructure complexity increases, IaC becomes the backbone of consistent deployments, compliance enforcement, and operational agility. The developer’s experience around IaC, however, remains fragmented — engineers routinely context-switch between documentation portals, linting tools, deployment consoles, and logging systems just to complete a single deploy cycle. This friction compounds across teams: slower iteration means delayed feature releases, longer incident recovery times, and increased operational risk. When a deployment fails, diagnosing the root cause across disconnected interfaces can take longer than writing the template itself — turning a feedback loop that could take hours of manual investigation into a more streamlined process.

The AWS Infrastructure as Code (IaC) MCP Server brings AWS CloudFormation documentation search, template validation, and deployment troubleshooting into your AI assistant, so you can move through a full AWS CloudFormation development cycle without leaving the chat interface. Developing AWS CloudFormation templates often means switching between documentation pages, linters, the deployment console, and AWS CloudTrail Logs. Each context switch adds friction to the inner development loop — the tight cycle of writing, validating, deploying, and fixing infrastructure code. This fragmented workflow increases time-to-deployment, delays feedback, and reduces developer productivity, particularly for teams managing complex, multi-resource stacks at scale.

The AWS Infrastructure as Code (IaC) Model Context Protocol (MCP) Server unifies these capabilities in one place. This post demonstrates how the IaC MCP Server tools work together in a real workflow — from authoring and validation through deployment and runtime troubleshooting — all within a single AI assistant conversation.

In this post, you can move through a complete CloudFormation development cycle using your AI assistant. You generate a template for an Amazon Simple Storage Service (Amazon S3) bucket, an AWS Lambda function, an AWS Identity and Access Management (IAM) execution role, and an Amazon CloudWatch Logs log group. You then validate, deploy, diagnose a deployment failure, and redeploy, all in a single interface.

Solution overview

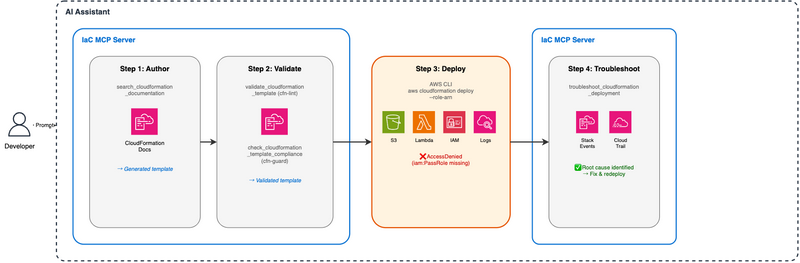
The walkthrough follows four steps that map to IaC MCP Server tools:

  1. Author: Search CloudFormation documentation and generate a template
  2. Validate: Check syntax with cfn-lint and compliance with cfn-guard
  3. Deploy: Deploy the stack using a CloudFormation service role
  4. Troubleshoot: Diagnose a deployment failure using CloudTrail correlation

Figure 1 shows the four-step workflow. Steps 1, 2, and 4 run inside the IaC MCP Server, while Step 3 uses the AWS CLI directly.

Architecture diagram showing the end-to-end CloudFormation workflow. You send a prompt to your AI assistant. Inside the AI assistant, the IaC MCP Server handles Step 1 (Author using search_cloudformation_documentation), Step 2 (Validate using cfn-lint and cfn-guard), and Step 4 (Troubleshoot using stack events and CloudTrail). Step 3 (Deploy) runs outside the IaC MCP Server using the AWS CLI with a CloudFormation service role.

Figure 1. End-to-end CloudFormation workflow with the IaC MCP Server

In the prerequisites, you deploy a CloudFormation service role stack that deliberately omits the iam:PassRole permission. During the walkthrough, you use the AI assistant to generate and deploy an application stack. When CloudFormation tries to assign the Lambda execution role, the deployment fails with AccessDenied. The troubleshoot tool then correlates stack events with CloudTrail to pinpoint the root cause.

For an introduction to each IaC MCP Server tool, see Introducing the AWS Infrastructure as Code MCP Server.

Prerequisites

Before you start the walkthrough, set up your AWS account and AI assistant and deploy the service role stack that the walkthrough depends on.

To follow along, you need:

This walkthrough uses the us-east-1 Region. You can use a different Region, but make sure to use the same Region consistently across each step.

Clone the companion repository and deploy the service role stack:

git clone https://github.com/aws-samples/sample-accelerate-cloudformation-with-iac-mcp-server.git

cd sample-accelerate-cloudformation-with-iac-mcp-server

aws cloudformation deploy \
  --template-file iac-mcp-blog-role-stack.yaml \
  --stack-name iac-mcp-blog-role-stack \
  --capabilities CAPABILITY_NAMED_IAM

This role grants CloudFormation permission to create S3 buckets, Lambda functions, and CloudWatch Logs log groups, but deliberately omits iam:PassRole — you’ll diagnose this gap in Step 4.

You use the --capabilities CAPABILITY_NAMED_IAM flag to acknowledge that the stack creates IAM resources with custom names.

We provide this role template for demonstration purposes only and do not intend it for production use.

Note the role ARN from the stack outputs. You must use this ARN in Step 3:

aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text

Walkthrough

The four steps that follow map to IaC MCP Server tools: authoring with documentation search, validating with cfn-lint and cfn-guard, deploying with a CloudFormation service role, and troubleshooting with CloudTrail correlation.

Step 1: Generate a CloudFormation template

Start by asking your AI assistant to search CloudFormation documentation and generate a template. The IaC MCP Server calls the search_cloudformation_documentation tool behind the scenes to retrieve up-to-date resource property references.

Prompt:

Create a CloudFormation template with an S3 bucket, a Lambda function (Python 3.13 runtime, inline hello-world code), an IAM execution role for the function, and a CloudWatch Logs log group. Include common security configurations. Save it as iac-mcp-blog-app-stack.yaml in the current directory.

The AI assistant calls the search_cloudformation_documentation tool to look up resource properties for AWS::S3::Bucket, AWS::Lambda::Function, AWS::IAM::Role, and AWS::Logs::LogGroup. You can see the tool invocations in Kiro’s chat interface. The search results include up-to-date property references and example configurations, which the AI assistant uses to generate a template.

The generated template should include resources similar to the following (your output may vary):

  • An S3 bucket with versioning, encryption, and public access block
  • A Lambda function with inline Python code
  • An IAM role with a least-privilege policy for CloudWatch Logs
  • A log group with a retention policy

The following snippet shows the key resources. Your AI assistant’s output may differ in naming or structure, but the core configuration should be similar:

Resources:
  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      BucketEncryption:
        ServerSideEncryptionConfiguration:
          - ServerSideEncryptionByDefault:
              SSEAlgorithm: AES256
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        BlockPublicPolicy: true
        IgnorePublicAcls: true
        RestrictPublicBuckets: true
      VersioningConfiguration:
        Status: Enabled

  LambdaFunction:
    Type: AWS::Lambda::Function
    Properties:
      Runtime: python3.13
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          def handler(event, context):
              return {"statusCode": 200, "body": "Hello from Lambda!"}

Step 2: Validate the template

Before deploying, ask the AI assistant to validate the template. The IaC MCP Server provides two validation tools that wrap open source checkers: cfn-lint for syntax validation and cfn-guard for policy-as-code compliance checks.

Prompt:

Validate iac-mcp-blog-app-stack.yaml for syntax errors and compliance violations.

The AI assistant runs two checks:

  1. Syntax validation (validate_cloudformation_template): Uses cfn-lint to catch structural errors, invalid property names, and schema violations.
  2. Compliance check (check_cloudformation_template_compliance): Uses cfn-guard to evaluate the template against security rules such as S3 bucket encryption, public access block settings, and log group retention.

If either check reports issues, ask the AI assistant to fix them. Continue iterating until both checks pass.

Note that the compliance check might flag violations related to S3 object lock, access logging, replication, and inline IAM policies. For a production workload, you would address each of these issues. In this walkthrough, the AI assistant resolves them to demonstrate the iterative validate-and-fix workflow. Your results might vary depending on the template the AI assistant generated in Step 1.

After the AI assistant resolves the violations, the S3 bucket resource gains access logging and object lock properties. The following snippet shows the typical shape of these additions (see iac-mcp-blog-app-stack-fixed.yaml in the companion repository for the complete hardened template):

  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      # ... existing properties ...
      LoggingConfiguration:
        DestinationBucketName: !Ref S3LoggingBucket
        LogFilePrefix: access-logs/
      ObjectLockEnabled: true
      ObjectLockConfiguration:
        ObjectLockEnabled: Enabled
        Rule:
          DefaultRetention:
            Mode: GOVERNANCE
            Days: 30

Your template now passes both cfn-lint and cfn-guard checks. These security improvements improve your template’s security posture but are unrelated to the deployment failure you’ll encounter next. The failure in Step 3 is caused by missing permission on the service role, not by anything in the template itself.

Step 3: Deploy the stack

With validation complete, deploy the template. This deployment will fail — not because of a template error, but because the CloudFormation service role deployed in the prerequisites is missing iam:PassRole. This is the scenario you’ll diagnose in Step 4.

Now deploy the validated template using the service role you created in the prerequisites:

Prompt:

Deploy iac-mcp-blog-app-stack.yaml as a stack named “iac-mcp-blog-app-stack” in us-east-1 using the service role ARN from iac-mcp-blog-role-stack.

The AI assistant runs the AWS CLI deployment command for you. If your AI assistant doesn’t support running shell commands directly, you can deploy manually with the AWS CLI:

Manual CLI deployment

ROLE_ARN=$(aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text)

aws cloudformation deploy \
  --template-file iac-mcp-blog-app-stack.yaml \
  --stack-name iac-mcp-blog-app-stack \
  --role-arn $ROLE_ARN \
  --capabilities CAPABILITY_NAMED_IAM

The deployment fails. The stack event shows an AccessDenied error on the IAM role resource, but doesn’t identify which permission on the CloudFormation service role is missing or why. At this point, we move from static analysis to runtime troubleshooting.

Step 4: Troubleshoot the failure

Ask the AI assistant to diagnose the failure:

⚠ Note: CloudTrail events typically take 5–15 minutes to appear. Wait at least 5 minutes after the deployment failure before running the troubleshoot tool for the most complete analysis.

Prompt:

Troubleshoot the failed deployment of iac-mcp-blog-app-stack in us-east-1.

The AI assistant calls troubleshoot_cloudformation_deployment, which:

  1. Retrieves the stack events and identifies the failed resources
  2. Correlates the failure timestamps with CloudTrail API calls
  3. Identifies AccessDenied errors and the missing permissions that caused them

The troubleshoot tool identifies that the CloudFormation service role is missing iam:PassRole — the permission required to assign the Lambda execution role to the function. If your template includes the cfn-guard hardening from Step 2 (access logging, object lock), the tool may also surface additional missing S3 permissions such as s3:PutBucketObjectLockConfiguration for the logging bucket.

Prompt:

Fix iac-mcp-blog-role-stack.yaml to add the missing permissions identified by the troubleshoot tool. Save it as iac-mcp-blog-role-stack-fixed.yaml.

The AI assistant adds the missing permissions to the service role template. Now ask the AI assistant to deploy the fix, delete the failed stack, and redeploy:

Prompt:

Deploy iac-mcp-blog-role-stack-fixed.yaml to update iac-mcp-blog-role-stack, then delete the failed iac-mcp-blog-app-stack and redeploy it with the same service role.

The AI assistant runs the necessary CLI commands: updating the role stack, deleting the failed application stack, and redeploying the application stack. The failed stack is in ROLLBACK_COMPLETE state, a terminal state that CloudFormation cannot update in place, so you must delete it before redeploying.

The stack deployment succeeded.

Cost considerations

For information about costs associated with the resources in this walkthrough, including S3 storage, Lambda invocations, CloudWatch Logs, and CloudFormation operations, see AWS Pricing. Confirm that your account usage falls within any applicable free tier limits. If you enabled S3 access logging or object lock through the validation-and-fix workflow in Step 2, the logging bucket stores a small amount of access log data that falls under S3 standard pricing. See AWS Pricing for current rates and confirm that your account is within the Free Tier limits before you deploy.

Cleaning up

To avoid ongoing charges, delete both stacks.

Option A: Clean up with your AI assistant

Ask your AI assistant to run the cleanup for you. The IaC MCP Server lets the AI assistant inspect stack outputs, empty buckets, and delete both stacks in the correct order:

Clean up the iac-mcp-blog-app-stack and iac-mcp-blog-role-stack stacks in us-east-1. Empty any S3 buckets they created (including access log buckets) before deleting the application stack, then delete the role stack.

Option B: Clean up manually

Delete the application stack first because it was deployed with the service role:

⚠ Warning: If your template included access logging, the logging bucket may contain objects. CloudFormation cannot delete a non-empty bucket. Empty it first:

aws s3 rm s3://<logging-bucket-name> --recursive

Then proceed with stack deletion.

aws cloudformation delete-stack --stack-name iac-mcp-blog-app-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-app-stack

aws cloudformation delete-stack --stack-name iac-mcp-blog-role-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-role-stack

If any S3 bucket was created with DeletionPolicy: Retain or still contains objects (for example, server access logs), CloudFormation leaves it in place. Empty and delete those buckets from the S3 console or with aws s3 rb s3://<bucket-name> --force.

Next steps

If you manage CloudFormation infrastructure and find yourself losing time to context-switching between docs, linters, consoles, and logs, here’s how to streamline your workflow starting today:

  1. Set up the IaC MCP Server — Install and configure the IaC MCP Server with an MCP-compatible AI assistant such as Kiro to bring documentation search, validation, and troubleshooting into a single conversational interface.
  2. Run the walkthrough end-to-end — Clone the companion repository and follow this post step by step to experience the full author-validate-deploy-troubleshoot loop in your own AWS account.
  3. Integrate into your team’s workflow — Replace manual context-switching by embedding the IaC MCP Server’s tools into your day-to-day CloudFormation development process, reducing iteration time from hours to minutes.
  4. Extend to AWS CDK — Apply the same conversational workflow to CDK-based infrastructure using the IaC MCP Server’s CDK capabilities described in the introductory blog post.
  5. Contribute and share feedback — Report issues or suggest enhancements on the AWS MCP GitHub repository to help shape future capabilities.

Conclusion

In this walkthrough, you used the IaC MCP Server to move through a complete CloudFormation development cycle without leaving your AI assistant. The documentation search tool retrieved up-to-date resource property references that the AI assistant used to generate a template. The validation tools caught syntax errors and compliance gaps before deployment. When the deployment failed due to missing permissions on the service role (an issue that static analysis cannot detect), you used the troubleshoot tool to correlate stack events with CloudTrail and pinpoint the root cause in seconds.

By combining static validation with runtime diagnostics, you shorten your develop-validate-fix cycle for CloudFormation. Instead of switching between browser tabs, CLI sessions, and the CloudTrail console, you stay in one interface — turning a multi-step troubleshooting session that previously meant switching between consoles, CLI sessions, and CloudTrail into a few prompts in a single conversation.

To get started, explore the companion GitHub repository for the complete sample code. Learn more about the IaC MCP Server in the introductory blog post and the AWS CloudFormation documentation. To set up Kiro, visit kiro.dev.


About the authors

Shuto Yukawa is an Associate Delivery Consultant at AWS Professional Services. He helps customers modernize their applications and adopt cloud-native practices on AWS.

G SS Harsha Vardhan is an Associate Delivery Consultant at AWS Professional Services. He guides customers to migrate and transform their workloads to AWS, driving modernization across people, process, and technology.

[$] The beginning of a process-builder API

Post Syndicated from corbet original https://lwn.net/Articles/1086330/

The recent discussion on “spawn templates”
raised questions about whether it was time to provide an alternative to the
classic Unix fork()/exec() pattern for process creation.
One idea that was raised there was to shift the template pattern into an
interface that could be used to efficiently assemble new processes from
bare cloth, without duplicating the parent process. Preferably, that
interface would be able to implement posix_spawn().
Li Chen, the author of the spawn-template work, has now responded with a patch series
(written with significant LLM assistance) showing what a process-builder
API for Linux might look like.

The collective thoughts of the interwebz