I Signed an OSI Board Agreement in Anticipation of Election Results

Post Syndicated from Bradley M. Kuhn original http://ebb.org/bkuhn/blog/2025/03/19/a-sign-board-agreement.html

An Update Regarding the 2025 Open Source Initiative Elections

I’ve
explained in
other posts
that I ran for the 2025 Open Source Initative Board of
Directors in the “Affiliate” district.

Voting closed on MON 2025-03-17 at 10:00 US/Pacific. One hour later,
candidates were surprised to receive an email from OSI demanding
that all candidates sign a Board agreement before results were
posted. This was surprising because during mandatory orientation,
candidates were told the opposite: that a Board agreement need not be
signed until the Board formally appointed you as a Director (as the
elections are only advisory &mdash: OSI’s Board need not follow election
results in any event. It was also surprising because the deadline was a
mere 47 hours later (WED 2025-03-19 at 10:00 US/Pacific).

Many of us candidates attempted to get clarification over the last 46
hours, but OSI has
not
communicated clear answers in response to those requests
. Based on
these unclear responses, the best we can surmise is that OSI intends to
modify the ballots cast by Affiliates and Members to remove any candidate
who misses this new deadline. We are loathe to assume the worst, but
there’s little choice given the confusing responses and surprising change
in requirements and deadlines.

So, I decided to sign a Board Agreement with
OSI. Here
is the PDF that I just submitted to the OSI
. I emailed it to OSI
instead. OSI did recommend DocuSign, but
I refuse
to use proprietary software for my FOSS volunteer work
on moral and
ethical grounds0 (see my two keynotes
(FOSDEM
2019
, FOSDEM
2020
) (co-presented with Karen Sandler) on this subject for more info
on that).

My running mate on the Shared Platform for OSI Reform, Richard Fontana, also signed a Board Agreement
with OSI
before the deadline as well.


0
Chad Whitacre
has made
unfair criticism of my refusal tog use Docusign
as part of the
(apparently ongoing?) 2025 OSI Board election political campaign. I respond to
his comment here in this footnote (& further discussion is welcome
using the fediverse, AGPLv3-powered comment feature of my blog
). I’ve put it in this
footnote because Chad is not actually raising an issue about this
blog post’s primary content, but instead attempting
to reopen
the debate about Item 4 in the Shared Platform for OSI Reform
.
My response follows:

In addition to
the two keynotes
mentioned above, I propose these analogies that really are apt to
this situation:

  • Imagine if the Board of The Nature Conservancy told Directors they
    would be required, if elected, to use a car service to attend Board
    meetings. It’s easier, they argue, if everyone uses the same service and
    that way, we know you’re on your way, and we pay a group rate anyway. Some
    candidates for open Board seats retort that’s not environmentally sound,
    and insist — not even that other Board members must stop using the
    car service &mdash: but just that Directors who chose should be allowed to
    simply take public transit to the Board meeting — even though it
    might make them about five minutes late to the meeting. Are these Director
    candidates engaged in “passive-aggressive politicking”?
  • Imagine if the Board of Friends of Trees made a decision that all
    paperwork for the organization be printed on non-recycled paper made from
    freshly cut tree wood pulp. That paper is easier to move around, they say
    — and it’s easier to read what’s printed because of its quality.
    Some candidates for open Board seats run on a platform that says Board
    members should be allowed to get their print-outs on 100% post-consumer
    recycled paper for Board meetings. These candidates don’t insist that
    other Board members use the same paper, so, if these new Directors are
    seated, this will create extra work for staff because now they have to do
    two sets of print-outs to prep for Board meetings, and refill the machine
    with different paper in-between. Are these new Director candidates, when
    they speak up about why this position is important to them as a moral
    issue, a “a distracting waste of time”?
  • Imagine if the Board of the APSCA made the decision that Directors must
    work through lunch, and the majority of the Directors vote that they’ll get
    delivery from a restaurant that serves no vegan food whatsoever. Is it
    reasonable for this to be a non-negotiable requirement — such that
    the other Directors must work through lunch and just stay hungry? Or
    should they add a second restaurant option for the minority? After all,
    the ASPCA condemns animal cruelty but doesn’t go so far as to
    demand that everyone also be a vegan. Would the meat-eating directors then
    say something like “opposing cruelty to animals could be so much more
    than merely being vegan” to these other Directors?

I Signed an OSI Board Agreement in Anticipation of Election Results

Post Syndicated from Bradley M. Kuhn original http://ebb.org/bkuhn/blog/2025/03/19/a-sign-board-agreement.html

An Update Regarding the 2025 Open Source Initiative Elections

I’ve
explained in
other posts
that I ran for the 2025 Open Source Initative Board of
Directors in the “Affiliate” district.

Voting closed on MON 2025-03-17 at 10:00 US/Pacific. One hour later,
candidates were surprised to receive an email from OSI demanding
that all candidates sign a Board agreement before results were
posted. This was surprising because during mandatory orientation,
candidates were told the opposite: that a Board agreement need not be
signed until the Board formally appointed you as a Director (as the
elections are only advisory &mdash: OSI’s Board need not follow election
results in any event. It was also surprising because the deadline was a
mere 47 hours later (WED 2025-03-19 at 10:00 US/Pacific).

Many of us candidates attempted to get clarification over the last 46
hours, but OSI has
not
communicated clear answers in response to those requests
. Based on
these unclear responses, the best we can surmise is that OSI intends to
modify the ballots cast by Affiliates and Members to remove any candidate
who misses this new deadline. We are loathe to assume the worst, but
there’s little choice given the confusing responses and surprising change
in requirements and deadlines.

So, I decided to sign a Board Agreement with
OSI. Here
is the PDF that I just submitted to the OSI
. OSI recommended DocuSign,
but since I refuse to use proprietary software for my FOSS volunteer work,
I emailed it to OSI instead.

Задължително образование по самоомраза

Post Syndicated from Светла Енчева original https://www.toest.bg/zadulzhitelno-obrazovanie-po-samoomraza/

Задължително образование по самоомраза

Марко Марков се самоуби на 27 февруари 2025 г. Той беше един от основателите на ЛГБТИ организацията „Действие“. Смъртта му шокира мнозина. Не само защото Марко беше едва на 38 години. Нито само защото беше пример и вдъхновение за поколения активисти, дори за такива, които не го познаваха лично. А и защото на пръв поглед нищо в живота му не издаваше, че иска да умре. Беше се установил в Нидерландия, съжителстваше с любящ партньор, снимките, които публикуваше в социалните мрежи, излъчваха щастие.

Тази щастлива черупка обаче прикриваше изключителна крехкост и ранимост. И травми още от юношеските и младежките години. От опитите да бъде „излекуван“ от сексуалната си ориентация чрез екзорсизъм, през хомофобския побой в центъра на София и подигравателното отношение на институциите след това, до заплахите, преследването, нападенията и изобщо цялата омраза…

През годините, в които общувах с Марко, имах усещането, че активизмът го държи жив, осмисля съществуването му, помага му да приема себе си и да понася живота. Може и да съм грешала. Но вече в Нидерландия той споделя, че годините на активизъм в България са го изтощили и повече няма сили за това. Казва и че се чувства бежанец от родната си страна. Три години по-късно става бежанец от самия живот.

Чупливи хора

Марко съвсем не е единственият ЛГБТИ човек, когото познавам, който едва е носел тежестта на собственото си съществуване. Трудно ми е да преброя приятелите и познатите си, които цял живот се борят с депресии с устойчиви суицидни идеи – в резултат на неприемане, преживяно насилие, самоомраза.

Сещам се за жена на 20 и малко години – толкова млада, колкото беше Марко, когато се запознах с него. Тя е блестяща във всичко, с което се заема, и получава заслужени награди. Но не смее да разкрие сексуалната си ориентация пред семейството си и години наред ходи на психотерапия, за да е в състояние да приема себе си. Живее в непрестанни угризения, че не постъпва както трябва.

Друг млад познат печели популярност с име и пол, с които не се идентифицира. Защото родителите му могат някак да преглътнат, че детето им е лесбийка, но не и че е транс мъж.

Мисля си и за транс жена, която вече е на средна възраст, но се е отказала от перспективата да уреди живота си в страна, в която би била приета, защото трябва да се грижи за болните си родители. Бори се с бедността, защото никой не иска да я наеме на работа с женска външност и мъжко име в личната карта. Не излиза навън с месеци от страх да не я пребият, защото е транс.

Приятел пък цял живот не си е позволявал пълноценен личен живот заради майка си, за която се е грижил и от която е крил сексуалната си ориентация. А когато майка му умира, той е твърде болен, за да може да има пълноценен личен живот.

Приятелка, и то пълнолетна и даже висшистка, е била отвлечена от баща си за цял месец, заключена и с отнети лични документи – само защото е обичала друга жена.

Друга приятелка, прехвърлила 50-те, се опитва да е хем добра дъщеря на родител, който не приема сексуалната ѝ ориентация, хем добра партньорка на дългогодишната си приятелка. И непрекъснато се разкъсва от чувство на вина, че не е там, където трябва да бъде.

Познавам ЛГБТИ хора, чиито родители са се отказали от тях. И такива, които, макар да имат партньори, прекарват т.нар. семейни празници сами, защото връзките им не се вписват в стереотипа за „традиционно семейство“.

Сещам се за десетки хора, които емигрираха, за да се спасят от тукашната среда и да могат да бъдат себе си.

„Приносът“ на Закона за предучилищното и училищното образование

Повечето хора, за които разказах, са осъзнали сексуалната си ориентация или половата си идентичност, когато в България вече не е незаконно да си хомосексуален, бисексуален или трансджендър. Въпреки това те са били обект на хомофобия или трансфобия било в училище, било вкъщи, било на обществени места, било навсякъде.

С промените в Закона за предучилищното и училищното образование (ЗПУО) от 7 август 2024 г. на днешните ЛГБТИ деца и тийнейджъри официално им се казва, че те са втора категория хора. Законът на практика забранява всякакво изразяване на каквото и да е, свързано с „нетрадиционна сексуална ориентация и/или определяне на полова идентичност, различна от биологичната“. А „нетрадиционната сексуална ориентация“ се определя като „различни от общоприетите и заложените в българската правна традиция схващания за емоционално, романтично, сексуално или чувствено привличане между лица от противоположни полове“.

По този начин хиляди деца и тийнейджъри биват заклеймени като различни от общоприетото, а самото им съществуване е сведено до заплаха, „пропаганда“ и „подстрекаване“. Това няма как да не причини дълбоки травми у много от тях. Освен това законовите промени дават зелена светлина за легитимиране на тормоза над ЛГБТИ учениците, което от своя страна води до още травми.

Опасността от задължителното обучение по религия

Един от приоритетите на настоящия министър на образованието Красимир Вълчев (ГЕРБ) е обучението по религия в училище да стане задължително, а не избираемо, както е в момента. Инициативата има сериозни шансове да мине в парламента. Става дума не за религия по принцип, а конкретно за православно християнство.

В ЗПУО се забранява „налагането на идеологически и/или религиозни доктрини“ в системата на образованието. Обучението по религия обаче се води неконфесионално, тоест не е насочено непременно към вярващи православни християни. В същото време обаче, ако хвърлим поглед върху програмата на предмета религия – въпреки общите приказки в началото за толерантност между отделните религии и към невярващите, става дума за

индоктриниране в православие.

От един първокласник например се очаква да „осъзнава, че Бог е всемогъщ и може да върши чудеса“, да „разбира, че всички хора са деца на Бога и Той се грижи за нас“, и „да разбира за любовта на Бога чрез примера на Иисус Христос“. Тук не става дума просто за познаване на религиозно учение – напротив, става дума за вяра.

В програмата много се говори за любов – на Бога към човека, на човека към Бога, към ближния. От второкласниците дори се очаква да разбират, „че любовта на Бога не се спечелва с омраза към неговите създания“.

В девети клас обаче идва темата за половото разделение в контекста на Стария завет. От един деветокласник се изисква да:

  • знае, че според Свещеното Писание човекът се дели на два пола (половинки): мъж и жена – единството на човека в брака;
  • знае, че еднополовите сексуални отношения според Закона се наказват със смърт (Лев. 20:13).
Задължително образование по самоомраза

Това впрочем е единственият пример за грях, който се дава в цялата учебна програма, като изключим първородния – той обаче не е индивидуален. Въпреки че според Стария завет какво ли не е грях – от предбрачния и извънбрачния секс, през нечестивите помисли, та до лихварството, без което съвременната икономика би била невъзможна. И именно защото грехът е неизбежен, идва Христос, за да плати със смъртта си за греховете на всички.

От деветокласниците също се очаква да разбират, че „грехът води до страдание и смърт“.

Как посланието на това учебно съдържание ще отекне у един 15-ина годишен ЛГБТИ тийнейджър, който го приема сериозно? „Ти си грешен, ти заслужаваш страдание и смърт.“ Освен ако по някакъв начин не се „поправи“, което няма как да стане, защото човек не си избира сексуалната ориентация и половата идентичност. Нито може да ги променя с пост, молитва и разкаяние.

Каква по-сигурна рецепта за депресия с устойчиви мисли за самоубийство?

Марковчета в масово производство

Заради популизъм и пропаганда българската образователна система все повече се превръща в машина за производство на марковчета – на ЛГБТИ младежи, пречупени още в крехка възраст. Те ще пораснат (ако доживеят порастването) като хора, които цял живот ще се борят не само с агресията и неприемането от страна на другите, а със самоомразата и неприемането на себе си. С непоносимостта към живота, с усилието да се събуждат сутрин отново и отново и да виждат някакъв смисъл да продължават, въпреки че усещат само болка. С невъзможността да бъдат щастливи, дори да са намерили споделена любов и приемаща среда.

Не, това не е начин да се създава здраво общество, нито да се възпитава любов към родината. Упражненията на политическия популизъм върху хора в крехка възраст ще доведат най-много до още омраза и разделение, травми, емиграция и самоубийства.

Съдба, свобода и игрова механика. Случаят „Индика“

Post Syndicated from original https://www.toest.bg/sudba-svoboda-i-igrova-mehanika-sluchayat-indika/

Съдба, свобода и игрова механика. Случаят „Индика“

Миглена Николчина: Много игри започват с амнезия на главния персонаж, аватара на играча. Това е тема сама по себе си. По отношение на „Индика“ обаче тази тема ще въведа аз. Сякаш убиецът Разколников и проститутката светица Соня Мармеладова от „Престъпление и наказание“ са забравили обещанието тя да го последва по пътя му към Сибир и към духовното му обновление, но ето че случайност, фатум или божият промисъл ги събира: влакът със затворниците катастрофира, той се оказва на свобода, траекториите на двамата се засичат и те безпаметно продължават онова, което са си обещали.

Едва ли е случайно, че Индика и Иля визуално са толкова подобни на актьорите от екранизацията от 1969 г. Само че не престъпникът, а грешницата се оказва на фокус. И докато бунтът на Разколников у Достоевски се осъществява като разразяване на свободната му воля под формата на едно „убийство с теория“ (за престъплението на Иля не забелязах да ни е казано нещо конкретно, освен че се движи в среда на крадци и убийци – той е по-скоро в ролята на сляпо вярващата Соня), бунтът на монахинята Индика е срещу свободната воля. Тя не желае свободна воля, тя протестира защо не е била създадена такава, че бог директно да я обикне, без усилие от нейна страна… а вместо това е обладана от демона на отрицанието, чийто (великолепно озвучен и на руски, и на английски) глас непрестанно дудне в нея и който от време на време се показва и действа от нейно име…

Тази педагогическа притча попада и в други матрици – на търсенето на чудо, което изпълнява желанията, както е в „Сталкер“ или в преобръщащия „Сталкер“ филм от 2011 г. – „Мишената“. Ако Индика разговаря с дявола, от когото иска да се отърве, Иля разговаря с бога и парадоксално вярва едновременно в свободата си и в предначертаността на всичко: двамата ще се съберат в надеждата си за чудо. Засега обаче ще оставя тези теми, за да те попитам какво мислиш за собствено игровите, лудическите особености на тази игра. Индика за мое изумление се оказа име на практически непозната византийска светица, но преди да намеря тази връзка, се чудех дали асоциацията не трябва да е с „инди“, което би превърнало играта в притча за самия жанр… Защо въобще е трябвало да е игра, а не филм например? Игровото в нея е поразително и според мен абсолютно преобръщащо много от нагласите ни, но как всъщност работи то?

Играта ни държи в железни клещи, към нашата свободна воля като играчи тя се отнася крайно иронично. Не ни е подадено да избираме отговори към нито една реплика от пестеливите, но изключително наситени диалози. Никакви сюжетни разклонения. Никакви удоволствени излишъци. Много малко възможности за мърдане насам-натам по картата. Пестелива формална строгост на всички нива. Автоматично запазване. Игровите отрязъци – ребуси, препятствия – или не са особено трудни, или ако са трудни, са вбесяващо монотонни. И все пак те са вписани в дългите филмови отрязъци по толкова органичен начин, че ме карат да ги мисля като рефункционализиране на игровата интерактивност. Можем ли да кажем, че работят като метафори, като реторически фигури, като параболично удвояване на случващото се в играта? Да започнем с рязко различаващите се по механиката и стилистиката си линии на странстването на Индика и Иля и на ретроспекциите на Индика. Как да тълкуваме тази разлика?

Сeверина Станкева: Аз мисля, че „Индика“ е притча не само за самия жанр, а за игровата структура изобщо, дори отвъд видеоигрите. Тя работи на поне три нива и представлява точно обратното на това, което изследователите на видеоигри малко подвеждащо наричат лудонаративен дисонанс – несъвпадение на повествованието и игровата механика. Типичен пример за дисонантна игра е „Последните от нас“, където разказът се концентрира върху моралните дилеми на главния герой в постапокалиптичен свят на зомби зараза, а в същото време играчът прекарва времето си, поемайки контрол над този герой, да убива всичко живо и неживо, без въобще да е поставен в позиция да се двоуми. При „Индика“, обратно, имаме лудонаративен консонанс, който свидетелства за това, че елементите, смятани обикновено за чисто лудически – менюта, дизайн на нива, постижения и прочее, – всъщност могат да функционират именно като инструменти на разказа.

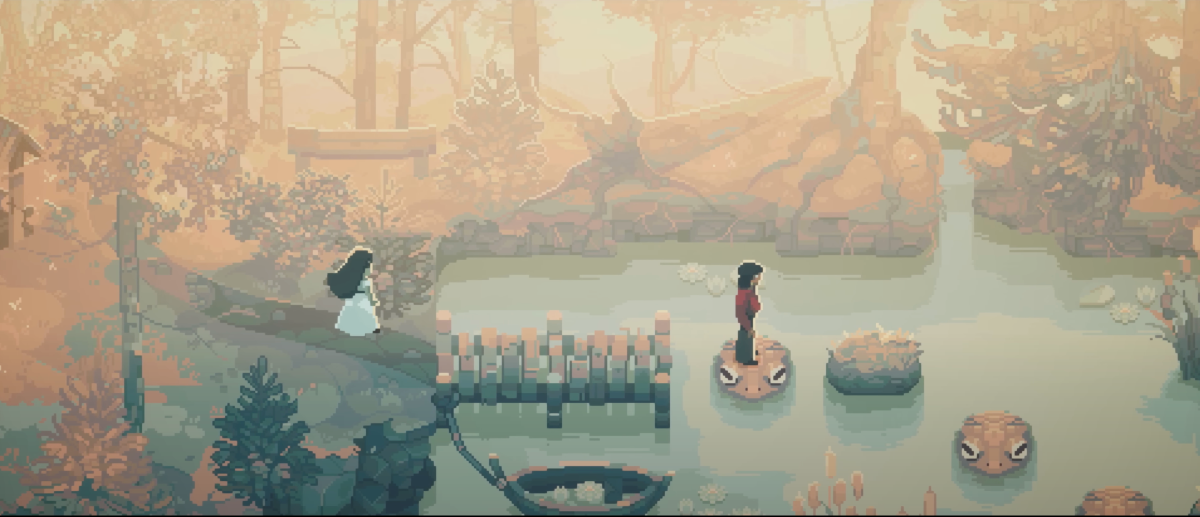
Ще започна оттам, откъдето предлагаш – стилистичният контраст на хиперреализма на „настоящето“ на играта, която се развива в православния бит и зима на нещо като Русия през XIX век, и миналото на главната героиня, монахинята Индика, представено в 32-битова рудиментарна многоцветност. От една страна, разбира се, този контраст може да се разгледа като любовно писмо до историята на видеоигрите и историята на свръхбързия им технологичен напредък. От друга обаче, пикселизираният стил е избран именно за спомените на Индика, защото най-добре приляга на изобразяването им – те са емоционално, тоест цветово наситени и носят носталгичен привкус, но детайлите им са се изтрили. В този смисъл те не могат да бъдат реалистични. Настоящето, напротив, е рязко и изпълнено с монотонни, досадни задачи, които, както съобщава невидимият в началото демон разказвач, са устоите на духовния живот.

Религията е представена като геймификация. Вършейки правоверни дела, които са изключително бавни – палейки свещи, кръстейки се, носейки вода във ведра, които после биват изливани на земята, събирайки религиозни артефакти, – Индика трупа точки, с които вдига нива, които ѝ носят още повече точки, и така нататък. Играчът може да избира в каква посока да употребява тези точки, но те в крайна сметка нямат никакво значение. Това е не просто циничен коментар върху религиозния живот, но и върху игрите въобще, или поне тази практика, която ги превръща в безсмислен труд и/или вехтошарство.

Той е отразен дори в трофеите, които могат да бъдат спечелени и които изискват също толкова целенасочено безумни действия – Индика трябва да се удави пет пъти в езерото, пет пъти да падне от сушилнята за риба, пет пъти да удари пиано в стената, за да спечели купата „Рахманинов“, и пр. Тази ирония е директно насочена към ловците на трофеи, които наброяват значителна част от играчите. Движенията на героинята също са именно нейни движения, тя е бавна, не може да тича, освен ако никой не я наблюдава (защото не подобава на една монахиня да тича), не се бие, трудно се катери. Въобще, играчът едва ли не чувства в процеса на игра рестрикциите на расото, което тя носи.

Но коментарът относно религията не е просто метакоментар, отразяващ мнението на разработчиците, и тук, струва ми се, повечето интерпретатори на играта не отиват достатъчно далеч. Той идва именно от дявола, който монахините от манастира са убедени, че се е вселил в Индика, и който всъщност е играчът. Бунтът на Индика срещу свободната воля парадоксално идва от място на несвобода. Да, на пръв поглед аватарът на играча е Индика и той наистина я управлява, но той е нея само в една кратка част към края, когато камерата преминава в първо лице и Индика едновременно приема присъствието му и успява да се отърве от него. През цялото останало време играта използва третото лице, монахинята се вижда отзад и леко отгоре.

Повечето игри не поставят под въпрос дистанцията, която този подход създава между аватара и играча, но не такъв е случаят тук. В този аспект играта е достоен наследник на „Хелблейд“ и психотичната ѝ главна героиня Сенуа, която е обладана от множество гласове, разпознаващи играчa като един от тях, макар и постепенно да се оказва, че това не е толкова просто.

Връщайки се към Индика, ако камерата се обърне към нея, се вижда как тя се озърта, все едно знае, че я наблюдават, или си дъвче ноктите от притеснение. Това е още по-ярко изобразено в някои от киноотрязъците, където „обективът“ е тип рибешко око, гледащо в гротескна и разкривена перспектива изпод брадичката на монахинята обратно към нея. В няколко ключови брилянтни пъзела, в огледалото Индика вижда не себе си, а дявола, тоест играча. Дяволът играч е този, който определя действията ѝ като тягостни и безсмислени, но и който я кара да ги върши, като в същото време се подиграва и на себе си, и на нея. Кудецът – празният мистичен предмет на чудото, в последна сметка си свършва работата, защото намирането му рано или късно кара играча да спре да играе и по този начин освобождава героинята. В последния кадър на играта, завършваща пред огледало, се вижда как в момента, в който играчът престава да го разтръсква (жест, който е умишлено многозначителен) и се отказва от контрола, дяволът изчезва и Индика (о)става самата себе си. Такъв тип авторефлексия е рядкост и според мен е черта, която споделят най-добрите игри.

Миглена Николчина: Не ми беше хрумвало да се отъждествявам с дявола. Той и невидимият, нечуван от нас бог са част от „карето“ с Индика и Иля. Опасявам се, че ако сведем всичко до авторефлексивността на играта, ще я лишим от други нейни измерения. Игровите действия, които описваш като безсмислени, имат метафорични нива. Например за да стигне до Мирко, първия си детски любим, който е обещал да ѝ направи флейта „специално за нея“, Индика скача от жаба на жаба. Ще се превърне ли от целувката жабата в принц? Всъщност това е въпросът и на основния сюжет – жабите вече са изскочили във вид на кукли от детското съкровище на Иля, което той споделя с Индика. Това е моментът на най-голямата им близост, в следващата сцена тя ще го целуне, докато отрязва гангренясалата му ръка – ще се върна към това.

Контрастът между мрачния хиперреализъм, както го нарече, на линията на настоящето и инфантилната пикселизация на ретроспекциите – разлика във визията, звука, игродействието, поднасянето на диалога – има измерение, което по Блейк можем да определим като „песни на невинността“ и „песни на опита“. Ретроспекциите отразяват детската невинност, песента на агнеца. Тя ще бъде загубена. Черно-бялата естетизация на студ, мъртвина и разруха, „песента на тигъра“, превежда Индика и Иля през страховития опит – отново пестеливо, притчообразно поднесен – на срещи с непоносима материална и духовна деградация… Двете линии се събират в края, когато научаваме какъв е грехът на Индика: тя се е отрекла, предала е детския си любим – три пъти повтаря, като апостол Петър, „не го познавам“ – и баща ѝ го застрелва.

И тук е един от забележителните моменти, в които обичаен лудически компонент – събирането на точки и нива – се оказва не просто елемент на разказа, но и оня елемент в разказа, който бележи метаморфоза, преображение. Всичките точки, които сме събрали от безсмислените предмети и ритуали – при това в игровите указания сме предупреждавани, че няма смисъл да ги събираме, – Индика ги губи, когато предлага на тъмничаря секс срещу свободата си. (Оказва се, че иска да бъде свободна все пак!) Когато по-късно започва да разтръсква празния кудец като кутия със зарове, тя започва да си връща точките по показатели като вина, тъга, срам, съжаление, разкаяние, смирение… Трябва да минем сякаш повторно през „добиването на нива“, но не като предписани от ритуала „геймифицирани“ жестове, а лице в лице с празнотата, с мълчанието на бога, с липсата на гаранции и чудеса, с алеаторността, но и с вътрешните бездни, за да може да види Индика в огледалото себе си, а не външна демонична сила. И това, както посочваш, е процесът, в който тя става аз… третото лице е станало първо, тоест става нас, става Всекичовек от средновековните мистерии, но и намира своята автономност и уникалност. За да разберем този финал, струва ми се важно да отчетем разликата между религията като институция и християнското боготърсачество. Но този финал си остава отворен и за атеистичен, еретичен или въобще пренебрегващ тези въпроси прочит.

Стига ли този финал и до любовта? Във форумите виждам изказани съжаления, че не. Аз обаче не мисля, че можем да сме сигурни.

Съдба, свобода и игрова механика. Случаят „Индика“
Кадър от „Индика“

Северина Станкева: Разбира се, интерпретацията по-горе не е единствената и не е несъвместима с тази, предложена от теб, която е по-скоро екзистенциална (християнско- или атеистично-). Моята по-скоро беше насочена към въпроса ти защо това не е филм – ами няма как да бъде, просто това няма как да е същата история, ако го нямаше играча. Не става въпрос за счупване на четвъртата стена и уличаването на зрителя в съучастие – жест, който може да видим в „Забавни игри“ на Ханеке например, където, за да изкупи вината си и да спаси жертвите, зрителят трябва да се откаже да гледа. В случая с „Индика“ героинята не знае, че оръдието на съдбата, което я ръководи, образно казано, седи пред екран и натиска копчета. Съответно не е съвсем ясно какво става, ако той спре да играе – освобождава ли я, или я обрича.

Не съм сигурна къде е любовта и има ли я. И двамата възлюбени на Индика ми бяха крайно антипатични и изпитвах съжаление към нея, задето е принудена да си носи последствията от опитите им да я използват, не че тези опити остават успешни задълго. В случaя с Мирко я измъчва вина заради смъртта му. Но той, струва ми се, от самото начало се интересува от нея само за да окраде баща ѝ. Заради Иля, който ми се видя по-сложен, но също толкова неприятен, пък я затварят във въпросната килия, без тя да има каквото и да било участие в извършеното престъпление – смъртта на свещеника. Самият Иля си е на свобода през цялото време. Как според теб стига финалът до любовта?

(Следва продължение.)


В рубриката „Игромислие“ публикуваме разговори, в които се срещат, съпоставят и противопоставят различни гледни точки към многоизмерния, многожанров феномен на видеоигрите – не толкова като електронен спорт, колкото като нов синтез на изкуствата и като ново поле на общуване и социалност.

Failing upwards: the Twitter encrypted DM failure

Post Syndicated from Matthew Garrett original https://mjg59.dreamwidth.org/71188.html

Almost two years ago, Twitter launched encrypted direct messages. I wrote about their technical implementation at the time, and to the best of my knowledge nothing has changed. The short story is that the actual encryption primitives used are entirely normal and fine – messages are encrypted using AES, and the AES keys are exchanged via NIST P-256 elliptic curve asymmetric keys. The asymmetric keys are each associated with a specific device or browser owned by a user, so when you send a message to someone you encrypt the AES key with all of their asymmetric keys and then each device or browser can decrypt the message again. As long as the keys are managed appropriately, this is infeasible to break.

But how do you know what a user’s keys are? I also wrote about this last year – key distribution is a hard problem. In the Twitter DM case, you ask Twitter’s server, and if Twitter wants to intercept your messages they replace your key. The documentation for the feature basically admits this – if people with guns showed up there, they could very much compromise the protection in such a way that all future messages you sent were readable. It’s also impossible to prove that they’re not already doing this without every user verifying that the public keys Twitter hands out to other users correspond to the private keys they hold, something that Twitter provides no mechanism to do.

This isn’t the only weakness in the implementation. Twitter may not be able read the messages, but every encrypted DM is sent through exactly the same infrastructure as the unencrypted ones, so Twitter can see the time a message was sent, who it was sent to, and roughly how big it was. And because pictures and other attachments in Twitter DMs aren’t sent in-line but are instead replaced with links, the implementation would encrypt the links but not the attachments – this is “solved” by simply blocking attachments in encrypted DMs. There’s no forward secrecy – if a key is compromised it allows access to not only all new messages created with that key, but also all previous messages. If you log out of Twitter the keys are still stored by the browser, so if you can potentially be extracted and used to decrypt your communications. And there’s no group chat support at all, which is more a functional restriction than a conceptual one.

To be fair, these are hard problems to solve! Signal solves all of them, but Signal is the product of a large number of highly skilled experts in cryptography, and even so it’s taken years to achieve all of this. When Elon announced the launch of encrypted DMs he indicated that new features would be developed quickly – he’s since publicly mentioned the feature a grand total of once, in which he mentioned further feature development that just didn’t happen. None of the limitations mentioned in the documentation have been addressed in the 22 months since the feature was launched.

Why? Well, it turns out that the feature was developed by a total of two engineers, neither of whom is still employed at Twitter. The tech lead for the feature was Christopher Stanley, who was actually a SpaceX employee at the time. Since then he’s ended up at DOGE, where he apparently set off alarms when attempting to install Starlink, and who today is apparently being appointed to the board of Fannie Mae, a government-backed mortgage company.

Anyway. Use Signal.

comment count unavailable comments

Migrating your on-premises workloads to AWS Outposts Rack

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/migrating-your-on-premises-workloads-to-aws-outposts-rack-2/

This post is written by Craig Warburton, Senior Solutions Architect, Hybrid; Sedji Gaouaou, Senior Solutions Architect, Hybrid; and Brian Daugherty, Principal Solutions Architect, Hybrid.

Migrating workloads to AWS Outposts Rack offers you the opportunity to gain the benefits of cloud computing while keeping your data and applications on premises.

For organizations with strict data residency requirements, by deploying AWS infrastructure and services on premises, you can keep sensitive data and mission-critical applications within your own data centers or facilities, helping ensure compliance with data sovereignty laws and regulatory frameworks.

On the other hand, if your organization does not have stringent data residency requirements, you may opt for a hybrid approach, using both Outposts Rack and the AWS Regions. With this flexibility, you can process and store data in the most appropriate location based on factors such as latency, cost optimization, and application requirements.

In this post, we cover options to migrate your workloads to an Outposts Rack, taking into account your specific data residency requirements. We explore strategies, tools, and best practices to enable a successful migration tailored to your organization’s needs.

Overview

AWS has several services to help you migrate and rehost workloads, including AWS Migration Hub, AWS Application Migration Service, AWS Elastic Disaster Recovery. Alternatively, you can use backup and recovery solutions provided by AWS partners.

At AWS, we use the 7 Rs framework to help organizations evaluate and choose the appropriate migration strategy for moving applications and workloads to the AWS Cloud. The 7 Rs represent:

  1. Rehosting (rehost or lift and shift)
  2. Replatforming (lift, tinker, and shift)
  3. Repurchasing (republish or re-vendor)
  4. Refactoring (re-architecting)
  5. Retiring
  6. Retaining (revisit)
  7. Relocating (remigrate).

This post focuses on rehosting and the services available to help rehost on-premises applications to Outposts Rack.

Before getting started with any migration, AWS recommends a three-phase approach to migrating workloads to the cloud (AWS Region or Outposts Rack). The three phases are assess, mobilize, and migrate and modernize.

Figure 1: Diagram showing the three migration phases of assess, mobilize, and migrate and modernize

Figure 1: Diagram showing the three migration phases of assess, mobilize, and migrate and modernize

This post describes the steps that you can take in the migrate and modernize phase. However, the assess and mobilize phases are also critical to allow you to understand what applications are migrated, the dependencies between them, and the planning associated with how and when migration occurs.

Workload migration to Outposts Rack: With staging environment in a Region

After deploying an Outposts Rack to your desired on-premises location, you can perform migrations of on-premises systems and virtual machines using either Application Migration Service and AMI creation or third-party backup and recovery services. Both scenarios are described in the following sections.

Scenario 1: Using Application Migration Service with AMI creation

Application Migration Service is able to lift and shift a large number of physical or virtual servers without compatibility issues, performance disruption, or long cutover windows.

In this scenario, at least one Outposts Rack is deployed on premises with the following prerequisites:

  • An AWS Replication Agent installed on each source server
  • At least one Outposts Rack installed and activated
  • VPC in an AWS Region
  • Staging subnet for staging migrated instances
  • Cutover subnet to validating migrated instances
  • Extended VPC spanning Region to the Outposts Rack
  • Migrated resources subnet where instances will be deployed from AMIs

The following diagram shows the solution architecture including the prerequisites and the on-premises servers that will be migrated to the Outposts Rack.

Figure 2: Architecture diagram showing migration with Application Migration Service

Figure 2: Architecture diagram showing migration with Application Migration Service

Step 1: Outposts Rack configuration

You can work with AWS specialists to size your Outposts for your workload and application requirements. In this scenario, you don’t need additional Outposts Rack capacity for migration because the staging area will be deployed in the Region (see 1 in Figure 2).

Step 2: Prepare Application Migration service

Set up Application Migration Service from the console in the Region to which your Outposts Rack is anchored. If this is your first setup, then choose Get started on the Application Migration Service console. When creating the replication settings template, ensure that your staging area is using subnets in the anchor Region (see 2 in Figure 2).

Step 3: Install the AWS Replication Agent to the source servers or machines

For large migrations, source servers may have a wide variety of operating system versions and may be distributed across multiple data centers. Application Migration Service offers the MGN connector, a feature that allows you to automate running commands on your source environment. Finally, ensure that communication is possible between the agent and Application Migration Service (see 3 in Figure 2).

In the following image, there is an example of deploying the AWS Replication Agent providing the necessary parameters (AWS Region, AWS access key and AWS secret access key).

Figure 2: Architecture diagram showing migration with Application Migration Service

When the AWS Replication Agent is installed, the server is added to the Application Migration Service console. Next, it undergoes the initial syncronization process, which is completed when showing the Ready for testing lifecycle state in the Application Migration Service console.

Step 4: Configure launch settings

Prior to testing or cutting over an instance, you must configure the launch settings by creating Amazon Elastic Compute Cloud (Amazon EC2) launch templates, ensuring that your cutover subnet is selected and that you choose an available instance type (see 4 in Figure 2). The instance type right-sizing feature allows AWS Application Migration Service to launch a test or cutover instance type that best matches the hardware configuration of the source server, by selecting the Basic option, AWS Application Migration Service will launch a test or cutover AWS instance type that best matches the OS, CPU, and RAM of your source server.

Step 5: Install AWS Systems Manager Agent on your cutover instances. When the launch settings are defined, you must activate the post-launch actions for either a specific server or all the servers. You must leave the Install the Systems Manager agent and allow executing actions on launched servers option toggled on in order for post-launch actions to work. Untoggling the option would disallow Application Migration Service to install the AWS Systems Manager Agent on your servers, and post-launch actions would no longer be executed (see 5 in Figure 2).

Figure 3: Post-launch actions on the Application Migration Service console

Figure 3: Post-launch actions on the Application Migration Service console

Step 6: Testing and cutover in Region

When you have configured the launch settings for each source server, you are ready to launch the servers as test instances. Best practice is to test instances before cutover.

Figure 4: Application Migration Service console ready to launch test instances

Figure 4: Application Migration Service console ready to launch test instances

Finally, after completing the testing of all the source servers, you are ready for cutover (see 6 on Figure 2). Prior to launching cutover instances, check that the source servers are listed as Ready for cutover under Migration lifecycle and Healthy under Data replication status.

Figure 5: Application Migration Console ready for cutover

Figure 5: Application Migration Console ready for cutover

To launch the cutover instances, choose the instances you want to cutover and then choose Launch cutover instances under Cutover (see Figure 5). The Application Migration Service console indicates Cutover finalized when the cutover has completed successfully the chosen source servers’ Migration lifecycle column shows the Cutover complete status, the Data replication status column shows Disconnected, and the Next step column shows Mark as archived. The source servers have now been successfully migrated into AWS. You can now archive your source servers that have launched cutover instances.

Step 7: Create a Migration AMI

After migrating all your workloads in the region where the Outposts is anchored to, create Amazon Machine Images (AMI). When you create an AMI from an instance, Amazon EC2 powers down the instance before creating the AMI to make sure that everything on the instance is stopped and in a consistent state during the creation process. If you are confident that your instance is in a consistent state appropriate for AMI creation, you can tell Amazon EC2 not to power down and reboot the instance.

This step can be automated using an existing Post Launch Action.

Step 8: Launch instances on AWS Outposts

The final part is to launch your created AMIs to your Outposts. To identify the EC2 instances configured on your Outpost you can use the following AWS Command Line Interface (AWS CLI):

Outposts get-outpost-instance-types \

–outpost-id op-abcdefgh123456789

The output of this command lists the instance types and sizes configured on your Outpost:

InstanceTypes:

– InstanceType: c5.xlarge

– InstanceType: c5.4xlarge

– InstanceType: r5.2xlarge

– InstanceType: r5.4xlarge

With knowledge of the instance types configured, you can now determine how many of each are available. For example, the following AWS CLI command, which is run on the account that owns the Outpost, lists the number of c5.xlarge instances available for use:

aws cloudwatch get-metric-statistics \

–namespace AWS/Outposts \

–metric-name AvailableInstanceType_Count \

–statistics Average –period 3600 \

–start-time $(date -u -Iminutes -d ‘-1hour’) \

–end-time $(date -u -Iminutes) \

–dimensions \

Name=OutpostId,Value=op-abcdefgh123456789 \

Name=InstanceType,Value=c5.xlarge

This command returns:

Datapoints:

– Average: 10.0

Timestamp: ‘2024-04-10T10:39:00+00:00’

Unit: Count

Label: AvailableInstanceType_Count

The output indicates that there were (on average) 10 c5.xlarge instances available in the specified time period (one hour). Using the same command for the other instance types, you discover that there are also 20 c5.4xlarge, 10 r5.2xlarge, and 6 r5.4xlarge available for use in completing the necessary EC2 launch templates.

Scenario 2: Using partner backup and replication solutions

You may already be using a third-party or AWS Partner solution to create on-premises backups of bare-metal or virtualized systems. These solutions often use local disk-arrays or object stores to create tiered backups of systems covering restore-points going back years, days, or just a few hours or minutes.

These solutions may also have inherent capabilities to restore from these backups directly to the AWS. This enables migration of on-premises systems to EC2 instances deployed to Outposts Rack.

In the scenario illustrated in Figure 6, the partner backup and replication service (BR) creates backups (see 1 in Figure 6) of virtual machines to on-premises disk or object storage repositories. Using the service’s AWS integration, virtual machines can be restored (see 2 in Figure 6) to an EC2 instance deployed on Outposts Rack, which is also on-premises. The restoration may follow a process that uses helper instances and volumes (see 3 in Figure 6) during intermediate steps to create Amazon Elastic Block Store (Amazon EBS) snapshots (see 4 in Figure 6) and then AMIs of the systems being migrated (see 5 in Figure 6), which are ultimately deployed (see 6 in Figure 6) to Outposts Rack.

Figure 6: Architecture diagram of the partner backup and replication scenario

Figure 6: Architecture diagram of the partner backup and replication scenario

When deploying an AMI created from a restored instance you must specify the target VPC and subnet. These should be the VPC being extended to the Outpost and a subnet that has been created in that VPC on the Outpost. You also need to specify an EC2 instance type that is available on the Outpost, which can be discovered using the process described in the previous section.

Workload migration to Outposts Rack using AWS Elastic Disaster Recovery (DRS)

Data residency can be a critical consideration for organizations that collect and store sensitive information, such as personally identifiable information (PII), financial data, or medical records. AWS Elastic Disaster Recovery, supported on Outposts Rack, helps enable seamless replication of on-premises data to Outposts Rack and addresses data residency concerns by keeping data within your on-premises environment, using Amazon EBS and Amazon S3 on Outposts.

In this scenario, an Outpost Rack is deployed on-premises with the following prerequisites:

  • At least one Outposts Rack installed and activated
  • The Outposts Rack must be in Direct VPC Routing (DVR) mode
  • VPC extended to the Outposts Rack containing subnets for staging and target resources
  • Amazon S3 on Outposts (necessary for all Elastic Disaster Recovery replication destinations)
  • An AWS Replication Agent installed on each source server

The following diagram shows the solution architecture and includes the on-premises servers that are migrated from the local network to the Outposts Rack. It also includes the staging VPC used to deploy the replication servers on Outposts Rack, Amazon S3 on Outposts to store the local Amazon EBS snapshots, and the target VPC extended to Outposts Rack.

Figure 7: Architecture diagram for workflow migration to Outposts Rack

Figure 7: Architecture diagram for workflow migration to Outposts Rack

Step 1: Outposts Rack configuration

To use Elastic Disaster Recovery on Outposts Rack, you need to configure both Amazon EBS and Amazon S3 on Outposts to support continuous replication and point-in-time recovery for your workload needs (see 1 in Figure 7). Specifically, you need to size the Amazon EBS and Amazon S3 on Outposts capacity according to your workload capacity requirements and application interdependencies. To do this, you can define dependency groups: each dependency group is a collection of applications and their underlying infrastructure with technical or non-technical dependencies. A 2:1 ratio is recommended for the EBS volumes to be used for near-continuous replication, and a 1:1 ratio is recommended for the Amazon S3 on Outposts ratio for EBS snapshots. For example, to migrate 40 TB of workloads, you need to plan for 80 TB of EBS volumes and 40 TB of Amazon S3 on Outposts capacity.

Step 2: Extend VPC to your Outposts Rack

When your Outpost has been provisioned and is available, extend the necessary Amazon Virtual Private Cloud (Amazon VPC) connection to the Outpost from the Region by creating the desired staging and target subnets (see 2 in Figure 7).

Step 3: Prepare Elastic Disaster Recovery service

Prepare the Elastic Disaster Recovery service from the Console to set the default replication and launch settings. When defining these settings, make sure that the Outposts resources available are chosen for staging and target subnets and instance and storage type (see 3 in Figure 7).

Step 4: Install the AWS Replication Agent to the source servers or machines

The next phase is to install the AWS Replication Agent to the source servers and to make sure that communication is possible between the AWS Replication Agent and your Outposts replication subnet through the Outposts local gateway, which makes sure that replication traffic uses the local network (see 4 in Figure 7).

Step 5: Continuous block-level replication

Staging area resources are automatically created and managed by Elastic Disaster Recovery. When the AWS Replication Agent has been deployed, continuous block-level replication (compressed and encrypted in transit) occurs (see 5 in Figure 7) over the local network.

Step 6: Launch Outposts Rack resources

Finally, migrated instances can now be launched using Outposts Rack resources based on the launch settings defined previously (see 6 in Figure 7).

Conclusion

In this post, you have learned how to migrate your workloads from your on-premises environment to AWS Outposts Rack based on your specific data residency requirements. When you have the flexibility of using AWS Regional services, AWS migration services or partner solutions can be used with infrastructure already in place. If your data must stay on-premises, then using AWS Elastic Disaster Recovery allows you to migrate your data without using Regional services, allowing you to migrate to Outposts Rack without your data leaving the boundary of a certain geographic location.

To learn more about an end-to-end migration and modernization journey, visit the AWS Migration Hub.

2024 H2 IRAP report is now available on AWS Artifact for Australian customers

Post Syndicated from Patrick Chang original https://aws.amazon.com/blogs/security/2024-h2-irap-report-is-now-available-on-aws-artifact-for-australian-customers/

Amazon Web Services (AWS) is excited to announce that a new Information Security Registered Assessors Program (IRAP) report (2024 H2) is now available through AWS Artifact. An independent Australian Signals Directorate (ASD) certified IRAP assessor completed the IRAP assessment of AWS in February 2025.

The new IRAP report includes an additional six AWS services that are now assessed at the PROTECTED level under IRAP. This brings the total number of services assessed at the PROTECTED level to 164.

The following are the six newly assessed services:

For the full list of services, see the IRAP tab on the AWS Services in Scope by Compliance Program page.

AWS has developed an IRAP documentation pack to help Australian customers and their partners plan, architect, and assess risk for their workloads when they use AWS Cloud services.

We developed this pack in accordance with the Australian Cyber Security Centre (ACSC) Cloud Security Guidance and Cloud Assessment and Authorisation framework, which addresses guidance within the Australian Government’s Information Security Manual (ISM, September 2024 version), the Department of Home Affairs’ Protective Security Policy Framework (PSPF), and the Digital Transformation Agency’s Secure Cloud Strategy.

The IRAP pack on AWS Artifact also includes newly updated versions of the AWS Consumer Guide and the whitepaper Reference Architectures for ISM PROTECTED Workloads in the AWS Cloud.

Reach out to your AWS representatives to let us know which additional services you would like to see in scope for upcoming IRAP assessments. We strive to bring more services into scope at the PROTECTED level under IRAP to support your requirements.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Patrick Chang
Patrick Chang

Patrick is the APJ Audit Lead based in Sydney. He leads security audits, certifications, and compliance programs across the APJ region. He is a technology risk and audit professional with over a decade of experience. He is passionate about delivering assurance programs that build trust with customers and provide them assurance on cloud security.

Enable single-sign-on for Amazon WorkMail with IAM Identity Center and Okta Universal Directory

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/enable-single-sign-on-for-amazon-workmail-with-iam-identity-center-and-okta-universal-directory/

Securing your business email is more critical than ever in today’s digital workplace. To help you protect your users and data in Amazon WorkMail (WorkMail), we regularly introduce security features that give organizations more control and protection for their business email. Thanks to the recently announced integration between WorkMail and AWS Identity and Access Management (IAM) Identity Center (IAM IdC), WorkMail users can now enjoy single sign-on (SSO) via compatible 3rd party external identity providers including Okta Universal Directory (Okta), Microsoft Entra ID, Google Workspace, JumpCloud, OneLogin, Ping Identity products and Active Directory.

This blog post explains the specific steps needed to integrate WorkMail with Okta via IAM IdC. WorkMail customers who use other 3rd party identity providers that are compatible with IdC will also find this post useful alongside the AWS documentation for their specific identity source. Alternatively, WorkMail organization administrators who do not use an external identity provider, but wish to enable multi-factor-authentication (MFA) for WorkMail viaIAM IdC will find guidance in a different blog post.

By integrating WorkMail with Okta via IAM IdC, users benefit from the security, convenience, and familiarity of SSO when accessing their WorkMail inbox and calendars via the WorkMail web-app. WorkMail organization administrators benefit from the security and efficiency of managing WorkMail user additions, modifications, or removals via the Okta admin tools. More detailed information about this integration can be found in the IAM IdC documentation as well as in the WorkMail documentation.

Introduction

Email remains a critical business communication tool, yet it is also one of the most targeted entry points for cyber threats. A single compromised email account can expose sensitive business data, damage an organization’s reputation, and serve as a gateway for further cyber attacks. As traditional username and password authentication becomes increasingly inadequate, organizations must adopt stronger access controls to protect their users and communications.

You can enhance your WorkMail organization’s security and simplify user authentication with SSO and a familiar login experience by integrating WorkMail with IAM IdC and Okta. This (and similar) integrations provide a more seamless authentication experience and helps administrators enforce consistent security policies across their organization.
The integration between WorkMail, IAM IdC and Okta supports these industry standards:

WorkMail authentication options

When you first set up WorkMail, you use the built-in user directory which relies upon standard username | password authentication for the WorkMail web browser client as well as popular desktop and mobile email clients such as Microsoft Outlook, Apple Mail and Thunderbird.

WorkMail standard username/password

By default, WorkMail uses username | password authentication

The integration between IAM Identity Center and Okta uses the SCIM protocol to provision and map user attributes in Okta to named attributes in IAM IdC. Once enabled, user and group information from Okta is automatically synchronized with IAM IdC. IAM IdC in turn uses the SAML protocol to provide Okta users with a familiar and convenient SSO experience.

After integrating IAM IdC with Okta, WorkMail uses:

  1. Okta SSO for users of the WorkMail web-app.
  2. Personal access tokens (PAT) for users of desktop &/or mobile email applications.
WorkMail uses Okta SSO or PATs

After integration with IdC and Okta, WorkMail uses SSO (web-app) and username | PAT (desktop/mobile) for authentication

Prerequisites for the WorkMail, IAM IdC and Okta integration

  • Admin access to an AWS account
    • You can evaluate the integration in this post for a limited period of time using an AWS Free Tier Account
  • Admin access to an Amazon WorkMail Organization
    • The integration uses the email domain that is configured as WorkMail’s default
  • Admin access to Amazon IAM Identity Center
    • Or admin access to the IdC organization account
  • Your WorkMail and IAM Identity Center must be in the same AWS region
  • IAM Role with the security credentials needed to deploy AWS infrastructure via the AWS CDK
  • Administrator access to a fully functional Okta Identity account populated with users and (optionally) group(s) that you want to integrate and synchronize with IAM IdC and WorkMail.
  • Access to the AWS Samples GitHub repository, where you’ll find sample code that deploys via AWS CDK. This code sample deploys a customizable AWS Lambda initially configured to perform user synchronization between IAM IdC and WorkMail every 15 minutes.
  • A source code editor such as Visual Studio Code with your AWS admin credentials.

High-level Steps

  1. Configure Identity Center (See our documentation for detailed information).
  2. Configure Okta Identity integration with IAM Identity Center. See this post for more information
  3. Provision and synchronize Okta’s Groups (or Okta Users) with IAM Identity Center
  4. Configure WorkMail to use Identity Center
  5. Deploy the AWS CDK sample project found in aws-samples in GitHub
  6. Test user access to WorkMail with and without Okta SSO (web-app) and Personal Access Token (desktop & mobile email clients)
  7. Notify WorkMail users of upcoming changes to login procedures.
  8. Switch WorkMail Authentication Mode to IAM IdC.

Detailed Configuration Guidance

The instructions that follow walk you through the steps needed to integrate your Okta system with IAM IdC. Once IAM IdC is synchronizing with Okta, you’ll integrate IAM IdC with WorkMail. This process will keep your WorkMail organization’s users and groups synchronized with Okta. Once fully enabled, your WorkMail users will use their Otka SSO credentials to access the WorkMail web-client or a username and unique Personal Access Tokens to access desktop &/or mobile email clients. Let’s get started!

Configure Okta integration with IAM Identity Center (these steps have been adapted from this blog post)

    1. Open the Okta admin landing page in a new browser (tab).

Okta admin landing page

    1. Click the Applications Section in the left menu.
    2. Click on Applications in the dropdown menu.
    3. Click Browse App Catalog.

Applications page.

    1. Type AWS IAM Identity Center in the search box.
    2. Click on the app that matches AWS IAM Identity Center.

AWS IAM Identity Center

    1. Click Add Integration to initiate the integration process.

Add Integration button

    1. Type a memorable name (like Workshop AWS IAM Identity Center) for the application label, and click Done.

Application Labe

    1. Click on the Sign On tab, scroll down to view SAML Signing Certificates.

    1. Click Actions to download the certificate to your local machine. Keep the Okta Admin dashboard Open, you will need the SAML information found here to configure IdC in the next section.

Configure AWS IAM IdC

  1. In a new browser window (or tab), open the IAM IdC console in the same region as your WorkMail Organization (we’re using us-east-1).
  2. If this is your first time accessing IAM IdC, you’ll be greeted with the IdC console home page prompting you to “Enable IAM Identity Center”. Click Enable.

Enable IAM Identity Center

  1. Check that you are in the correct region, click Enable (note – this will enable an Organization instance of IdC, which is recommended. If you want to use an Account instance of IdC, please see the documentation).

enable an Organization instance of IdC

  1. Once IdC has been enabled, scroll down to the IAM Identity Center setup section and click Confirm Identity Source.

  1. Click Actions, and select Change identity source from dropdown menu.

Change identity source

  1. Select External identity provider and click Next.

External identity provider

  1. Upload the SAML certificate you downloaded from Okta (above, step xx)
  2. Open the Okta dashboard browser/tab. Under the SAML 2.0 configuration, scroll down and expand > More details.
    • Copy the Sign on URL from Okta SAML and paste the URL into the IdP sign-in URL field in IdC.
    • Copy the Issuer URL from Okta SAML and paste the URL into the IdP sign-in URL field in IdC.
    • Click Next.
  1. Type ACCEPT in the confirmation text box & click Change identity source.

Change identity source

  1. Switch back to the IAM IdC console browser window/tab. On the Settings page, locate the Automatic provisioning information box, and then choose Enable. Leave this browser window/tab open as you’ll need it to copy the values for the SCIM endpoint and Access token into Okta shortly (note – IdC Automatic provisioning uses SCIM protocol to provision users from Okta).

IdC Automatic provisioning

  1. Return to the Okta admin dashboard (you should have left it open in another browser window or tab). Under IAM Identity Center applications, select the Workshop AWS IAM Identity Center and open the Provisioning tab.
  2. Under Integration, click Configure API Integration.

Configure API Integration

  1. Select the checkbox next to Enable API integration to enable provisioning.
  2. Refer to the IAM IcC console browser window/tab you left open and copy (from IdC) and paste (into Okta) the values for:
    • Base URL field – paste the IdC SCIM endpoint value (make sure there is no trailing forward slash at the end of the URL).
    • API Token field, enter the Access token value.
    • Import Groups should be checked
  1. Click Test API Credentials to verify the credentials entered are valid (the message AWS IAM Identity Center was verified successfully! should appear).

AWS IAM Identity Center was verified successfully

  1. Save.
  2. Under Settings, choose To App, click Edit and select Enable for Create Users, Update User Attributes and Deactivate Users. Click Save.

Update User Attributes and Deactivate Users

  1. In the Okta admin dashboard’s left-hand menu pane, click on Directory.
    • Choose Groups to see the list of existing groups.
    • Click on the Add Group button to create a new group called workmail_users.
    • Fill in the required details for the new group, including:
      • Group Name: Enter workmail_users for the group.
      • Group Description (optional): Provide a description for the group’s purpose (WorkMail_users).
    • Save the New Group
    • Reload the page to see the newly created group
    • Click Assign people
    • Add Okta users to the workmail_users group
    • Click Save
  1. In the Okta admin dashboard’s left-hand menu pane, click on Applications and open the AWS IAM Identity Center application.
  2. Click the Assignments tab, choose Assign, then choose Assign to people.
  3. Choose the Okta users that you want to have access to WorkMail via IAM Identity Center app.
  4. For each user, click Assign, review the user info, and click Save then Go Back
  5. When all Okta users for whom you want WorkMail users created/synced have been assigned, click Done to start the process of provisioning the users into IAM Identity Center.

provisioning the users into IAM Identity Center

  1. On the Assignments page, choose Assign, and then choose Assign to groups.
  2. Click the Okta group (workmail_users) that you want to have access to WorkMail via IAM Identity Center.
  3. Click Assign, review the selections, click Save and Go Back. Click Done. This starts the process of provisioning the users in the workmail_users group into IAM Identity Center.
  4. Choose the Push Groups tab.
  5. Choose the workmail_users group that contains all the users that you assigned to the IAM Identity Center app.
  6. If the group is not found in the list, choose the Find groups by name option by clicking (+)Push Groups Menu.
  7. Enter the group name ( workmail_users) that you created in the previous step and select it from the search results
  8. Click Save. The group status changes to “pushing” then “Active” (this can take several minutes), once the Okta workmail_users group and all its members have been pushed to IAM Identity Center.
  9. Return to the browser window/tab with the IAM Identity Center console.
  10. In the left navigation, select Groups (or Users) (you should see the Group (or users) list that was just populated by the Okta “push” action).

elect Groups (or Users)

Enable IAM Identity Center in Amazon WorkMail

  1. Open a new browser window (tab) to the WorkMail console in the same region as IdC, and open your WorkMail Organization.
  2. In WorkMail’s left navigation rail click Identity Center
  3. Click on Multi-factor authentication setup guide, Click Enable Identity Center, read the default configuration notice ,and click Enable

Enable Identity Center

  1. Under Identity Center Settings, click the Authentication mode tab and ensure it is set for WorkMail directory and Identity center (this is the default).
  2. This mode is needed for testing and to allow desktop & mobile email client users to retrieve their unique personal access tokens.
  3. Once the integration with IdC is successfully tested, and those WorkMail users who rely on desktop or mobile email clients for access have had the opportunity to login to the WorkMail web app to retrieve a PAT, you will change the Authentication mode to Identity center only.

Deploy the sample solution from GitHub

Solution prerequisites:

– AWS Account
– AWS IAM user with Administrator permissions
– Python (> v3.x) and Pip fully installed and configured on your computer
– AWS CLI (v2) installed and configured on your computer
– AWS CDK (v2) installed and configured on your computer
– Sample CDK project that creates and deploys an AWS Lambda in your AWS account to perform users synchronization between IAM IdC and WorkMail.

The instructions that follow guide you in deploying a sample solution for the AWS Samples Serverless-Mail repository that programmatically creates/syncs WorkMail users from IAM Identity Center using the AWS CDK CLI. The sample uses naming conventions used in this blog. For example, the Lambda only syncs those users found in the IdC Group named "workmail_users". If your IdC group has a different name, or you want to sync multiple IdC groups with WorkMail, you will need to modify the sample code before proceeding. (BE AWARE: The sample code base is an Open Source starter project designed to provide a demonstration and a base to start from for specific use cases. It should not be considered fully Production-ready, nor should it be deployed in a production environment. Refer to the README.md and License.md for more information.)

  1. Clone the sample project to your computer (git clone https://github.com/aws-samples/serverless-mail/tree/main/idc_okta-workmail). CD into the ‘idc_okta-workmail‘ directory.
  2. Create a virtual environment for packaging in Python (Docker must already be running locally) with python3 -m venv .venv
  3. Activate the virtual environment with source .venv/bin/activate
  4. Make sure cdk.json references the correct path to Python (by default cdk.json refers to .venv/bin/python app.py). If you need to locate Python, run the which python command.
  5. Install the project dependencies with pip3 install -r requirements.txt
  6. Check the AWS CLI local credentials and region with aws sts get-caller-identity . If you need to change any parameter, run aws configure
  7. Prepare the `app.py` file by running python3 get-my-variables.py  . The ‘get-my-variables.py’ script fetches the necessary variables from your AWS account and create the `app.py` file needed by the CDK. You may want to review the auto-generated `app.py` file for accuracy, especially if the AWS account has been used for other IdC or WorkMail related projects. The app.py file requires the following account variables:
    • AWS accountId
    • AWS Region – the region must be the same for IdC and WorkMail.
    • IDENTITYSTORE_ID – – found in the Identity Center console under settings or via the AWS CLI aws identitystore list-groups --identity-store-id {identity_store_id}
    • IDENTITY_CENTER_INSTANCE_ARN – found in the Identity Center console under settings or via the AWS CLI aws sso-admin list-instances
    • IDENTITY_CENTER_APPLICATION_ARN – found in the Identity Center console under Applications or via the AWS CLI aws sso-admin list-applications --instance-arn {instance_arn}`
    • WORKMAIL_ORGANIZATION_ID – found in the WorkMail console under Organizations or via the AWS CLI aws workmail list-organizations
    • OKTA_GROUP_ID_TO_ASSIGN_TO_WORKMAIL – found in the Identity Center console under Groups > General Information or via the AWS CLI aws identitystore list-groups --identity-store-id {identity_store_id}
  8. Bootstrap the package (this step may take several minutes to complete) with cdk bootstrap
  9. Synthesize the package (this step may take several minutes to complete) with cdk synthesize
  10. Deploy your package (this step may take several minutes to complete) with cdk deploy and follow the prompts in the AWS CDK CLI.
  11. Once deployment to your AWS account starts, you can view the deployment status in the CloudFormation console.

Confirm WorkMail Authentication mode

WorkMail’s default Authentication mode should be set to WorkMail directory and Identity center. Don’t change this yet. This mode will allow WorkMail web-app users to continue to login to the WorkMail client directly, without Okta SSO. WorkMail’s Personal access token configuration default is set to active, and token lifespan set to 365 days. You can change this if your security needs differ from the default. PATs are used by desktop and mobile email clients to login to WorkMail. Leaving WorkMail’s default Authentication mode set to WorkMail directory allows desktop and mobile email clients to continue to login to the WorkMail with their username and password, without yet requiring a PAT instead of password.

Conduct a few spot tests to verify WorkMail web-app users can properly access their WorkMail accounts via:

  1. The Amazon WorkMail web application URL (found on the WorkMail organization page)

Webmail login link

  1. Your organization’s unique AWS access portal URL (found on the setting page of the IAM IdC dashboard).

  1. This will open a new browser tab that redirects to the Okta user login page.

Okta user login page

  1. Once user has authenticated, this page will redirect to the AWS access portal with linked application tiles to all of the AWS applications that have been integrated with IAM Identity Center.

AWS access portal with linked application tiles

  1. Click on the WorkMail logo, and the WorkMail web-app will load.

WorkMail web-app

  1. Desktop or mobile email software users need to create a WorkMail Personal Access Token (PAT) to access WorkMail. These users must retrieve their own PATs after logging into the WorkMail web-client. Open the Webmail login link found on the WorkMail Organization page under User Login

Webmail login link

  1. In the WorkMail web-app,
    1. click the settings gear (in top right)
    2. Click Personal Access token and enter a token name (i.e. desktop-thunderbird-pat)
    3. Click Create token.
    4. Click Create token.
    5. Copy the token value (this is the only time you can retrieve this token value).
  2. Open your desktop or mobile email software, enter your username and your PAT (the PAT replaces your existing user password).

WorkMail web-app

  1. In settings, click Personal Access token and Create token
  2. Enter a token name (typically the device on which you’ll use this PAT) and select create token.
  3. Copy the token value (this is the only time you can retrieve this token value).
  4. Open your desktop or mobile email software, enter your username and your PAT (the PAT replaces your existing user password), and test your new login (username | PAT).

enter your username and your PAT

Notify your WorkMail users of upcoming changes to login procedures

Once you have tested the integration between WorkMail and IAM Identity Center with a few test users, you should prepare your WorkMail users for the increased login security. For example, you could send them an email that explains:

  • The organization is adding an additional login security step to help protect their inboxes.
  • Inform them that they should anticipate an email from the AWS IAM Identity Center with info about the upcoming implementation of MFA for web-app users and PATs for desktop and mobile client users.
  • Users should accept the invitation and create a new password for the AWS IAM Identity Center.
  • Inform them that once WorkMail MFA is enabled, all WorkMail web-app users will be required to use their username, password and MFA.
  • Inform them that once WorkMail PATs are enabled, all WorkMail desktop and mobile email client users will need to login to the WorkMail web client (with MFA) via the AWS access portal URL, create one PAT per software client (the same PAT can not be used on desktop and mobile). They then must update their desktop or mobile email software to use their username and PAT, instead of their current password. Explain that the PAT is now their email client application password and their personal desktop or mobile email software passwords will no longer work.
  • Provide users with a way to request support.

Switch WorkMail Authentication Mode to Identity Center only

  1. Once you are satisfied that your WorkMail users have incorporated Okta SSO and/or PATs into their WorkMail login routines, the WorkMail administrator should disable the WorkMail directory Authentication mode found in the WorkMail console under Organization > Identity Center.

disable the WorkMail directory Authentication mode

  1. Optional – Ask several trusted users to test their ability to login to WorkMail web app via Okta credentials.

Congratulations, your WorkMail organization’s authentication is now being managed by IAM Identity Center and your external identity provider, Okta.

Conclusion

By integrating IAM Identity Center with Okta Identity and WorkMail, you can provide your users with the convenience of Okta SSO for the WorkMail web-app. This allows your organization to improve it’s email security posture, better safeguard sensitive communications and protect you WorkMail organization against unauthorized access. Furthermore, this integration reduces admin overhead as user access to WorkMail is allowed, or revoked via the Okta administration dashboard.

Take control of your email communications today with Amazon WorkMail:

  1. Visit the WorkMail Console to begin configuration.
  2. Enable IAM Identity Center Integration with Okta and WorkMail.
  3. Connect your WorkMail organization to centralized access management.
  4. Configure WorkMail to require:
    1. Okta SSO – Adds an extra layer of security for web-app users.
    2. Personal Access Tokens (PAT) – Add an extra layer of security for desktop and mobile client access.

Need guidance? Check out our technical documentation. Contact your AWS account team.

To help keep your WorkMail organization secure, we recommend:

  • Regularly reviewing your WorkMail audit logs for unexpected activity.
  • Monitoring for unauthorized access attempts.
  • Staying informed about the latest security practices.

Dive deeper into WorkMail security with these resources:

Join the Conversation:
Connect with other administrators and security professionals on the AWS re:Post community to share insights and learn best practices.

[$] Oxidizing Ubuntu: adopting Rust utilities by default

Post Syndicated from jzb original https://lwn.net/Articles/1014002/

If all goes according to plan, the Ubuntu project will soon be
replacing many of the traditional GNU utilities with implementations
written in Rust, such as those created by the uutils project, which we covered in
February. Wholesale replacement of core utilities at the heart of a
Linux distribution is no small matter, which is why Canonical’s VP of
engineering, Jon Seager, has released oxidizr. It
is a command-line utility that helps users easily enable or disable
the Rust-based utilities to test their suitability. Seager is calling
for help with testing and for users to provide feedback with their
experiences ahead of a possible switch for Ubuntu 25.10, an interim release
scheduled for October 2025. So far, responses from the Ubuntu
community seem positive if slightly skeptical of such a major
change.

AWS completes the annual UAE Information Assurance Regulation compliance assessment

Post Syndicated from Vishal Pabari original https://aws.amazon.com/blogs/security/aws-completes-the-annual-uae-information-assurance-regulation-compliance-assessment-2/

Amazon Web Services (AWS) is pleased to announce the publication of our annual compliance assessment report on the Information Assurance Regulation (IAR) established by the Telecommunications and Digital Government Regulatory Authority (TDRA) of the United Arab Emirates (UAE). The report covers the AWS Middle East (UAE) Region.

The IAR provides management and technical information security controls to help establish, implement, maintain, and continuously improve information assurance. AWS alignment with IAR requirements demonstrates our ongoing commitment to adhere to the heightened expectations for cloud service providers. As such, IAR-regulated customers can continue to use AWS services with confidence.

Independent third-party auditors from BDO evaluated AWS for the period of November 1, 2023, to October 31, 2024. The assessment report that illustrates the status of AWS compliance is available through AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about IAR compliance, reach out to your AWS account team.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Vishal Pabari
Vishal Pabari

Vishal is a Security Assurance Program Manager at AWS, based in London, UK. Vishal is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Vishal previously worked in risk and control, and technology in the financial services industry.

Implement Amazon EMR HBase Graceful Scaling

Post Syndicated from Yu-Ting Su original https://aws.amazon.com/blogs/big-data/implement-amazon-emr-hbase-graceful-scaling/

Apache HBase is a massively scalable, distributed big data store in the Apache Hadoop ecosystem. We can use Amazon EMR with HBase on top of Amazon Simple Storage Service (Amazon S3) for random, strictly consistent real-time access for tables with Apache Kylin. It ingests data through spark jobs and queries the HTables through Apache Kylin cubes. The HBase cluster uses HBase write-ahead logs (WAL) instead of Amazon EMR WAL.

A time goes by, companies may want to scale in long-running Amazon EMR HBase clusters because of issues such as Amazon Elastic Compute Cloud (Amazon EC2) scheduling events and budget concerns. Another issue is that companies may use Spot Instances and auto scaling for task nodes for short-term parallel computation power, like MapReduce tasks and spark executors. Amazon EMR also runs HBase region servers on task nodes for Amazon EMR on S3 clusters. Spot interruptions will lead to an unexpected shutdown on HBase region servers. For an Amazon EMR HBase cluster without enabling write-ahead logs (WAL) for Amazon EMR feature, an unexpected shutdown on HBase region servers will cause WAL splits with server recovery process, and it will bring extra load to the cluster and sometimes makes HTables inconsistent.

For these reasons, administrators look for a way to scale-in Amazon EMR HBase cluster gracefully and stop all HBase region servers on the task nodes.

This post demonstrates how to gracefully decommission target region servers programmatically. The scripts do the following tasks. The script also tests successfully in Amazon EMR 7.3.0, Amazon EMR 6.15.0, and 5.36.2.

  • Automatically move the HRegions through a script
  • Raise the decommission priority
  • Decommission HBase region servers gracefully
  • Prevent Amazon EMR provisioning region servers on task nodes by Amazon EMR software configurations
  • Prevent Amazon EMR provisioning region servers on task nodes by Amazon EMR steps

Overview of solution

For graceful scaling in, the script uses HBase built-in graceful_stop.sh to move regions to other region servers to avoid WAL splits when decommissioning nodes. The script uses HDFS CLI and web interface to make sure there are no missing and corrupted HDFS block during the scaling events. To prevent Amazon EMR provisions HBase region servers on task nodes, administrators need to specify software configurations per instance groups when launching a cluster. For existing clusters, administrators can either use a step to terminate HBase region servers on task nodes, or reconfigure the task instance group’s HBase storagerootdir.

Solution

For a running Amazon EMR cluster, administrators can use AWS Command Line Interface (AWS CLI) to issue a modify-instance-groups with EC2InstanceIdsToTerminate to terminate specified instances immediately. But terminating an instance in this way can cause a data loss and unpredictable cluster behavior when HDFS blocks have not enough copies or there are ongoing tasks on those decommissioned nodes. To avoid these risks, administrators can send a modify-instance-groups with a new instance request count without a specific instance ID that administrators want to terminate. This command triggers a graceful decommission process on the Amazon EMR side. However, Amazon EMR only supports graceful decommission for YARN and HDFS. Amazon EMR doesn’t support graceful decommission for HBase.

Hence, administrators can try method 1, as described later in this post, to raise the decommission priority of the decommission targets as the first step. In case tweaking the decommissions priority didn’t work, move forward to the second approach, method 2. Method 2 is to stop the resizing request, and move the HRegions manually before terminating the target core nodes. Note that Amazon EMR is a managed service. Amazon EMR service will terminate the EC2 instance after anyone stops it or detach its Amazon Elastic Block Store (Amazon EBS) volumes. Therefore, don’t try to detach EBS volumes on the decommission targets and attach them to new nodes.

Method 1: Decommission HBase region servers through resizing

To decommission Hadoop nodes, administrators can add decommission targets to HDFS’s and YARN’s exclude list, which were dfs.hosts.exclude and yarn.nodes.exclude.xml. However, Amazon EMR disallows manual update to these files. The reason is that the Amazon EMR service daemon, master instance controller, is the only valid process to update these two files on master nodes. Manual updates to these two files will be reset.

Thus, one of the most accessible ways to raise a core node’s decommission priority according to Amazon EMR is having less instance controller heartbeat.

As the first step, pass move_regions to the following script on Amazon S3, blog_HBase_graceful_decommission.sh, as an Amazon EMR step to move HRegions to other region servers and shutdown processes of region server and instance controller. Please also provide targetRS and S3Path to blog_HBase_graceful_decommission.sh. targetRS represents to the private DNS of the decommission target region server. S3Path represents the location of the region migration script.

This step needs to be run in off-peak hours. After all HRegions on the target region server are moved to other nodes, splitting WAL activities after stopping the HBase region server will generate a very low workload to the cluster because it serves 0 regions.

For more information , refer to blog_HBase_graceful_decommission.sh.

Taking a closer look at the move_regions option in blog_HBase_graceful_decommission.sh, this script disables the region balancer and moves the regions to other region servers. The script retrieves Secure Shell (SSH) credentials from AWS Secrets Manager to access worker nodes.

In addition, the script included some AWS CLI operations. Please make sure the instance profile, EMR_EC2_DefaultRole, can operate the following APIs and have SecretsManagaerReadWrite permission.

Amazon EMR APIs:

  • describe-cluster
  • list-instances
  • modify-instance-groups

Amazon S3 APIs:

  • cp

Secrets Manager APIs:

  • get-secret-value

In Amazon EMR 5.x, HBase on Amazon S3 will make the master node also work as a region server hosting hbase:meta regions. This script will get stuck when trying to move non-hbase:meta HRegions to the master. To automate the script, the parameter, maxthreads, is increased to move regions through multiple threads. By moving regions in a while loop, one of the threads got a runtime error because it tries to move non-hbase:meta HRegions to the master node. Other threads can keep on moving HRegions to other region servers. After the only stuck thread timed out after 300 seconds, it moves forward to the next run. After six retries, manual actions will be required, such as using a move action through the HBase shell for the remaining regions’ movement or resubmitting the step.

The following is the syntax to use the script to invoke the move_regions function through blog_HBase_graceful_decommission.sh as an Amazon EMR step:

Step type: Custom JAR
Name: Move HRegions
JAR location :s3://<region>.elasticmapreduce/libs/script-runner/script-runner.jar
Main class :None
Arguments :s3://yourbucket/your/step/location/blog_HBase_graceful_decommission.sh move_regions <your-secret-id> <targetRS: target_region_server_private_DNS> <S3Path: S3 location>
Action on failure:Continue

Here’s an Amazon EMR step example to move regions:

Step type: Custom JAR
Name: Move HRegions
JAR location :s3://us-west-2.elasticmapreduce/libs/script-runner/script-runner.jar
Main class :None
Arguments :s3://yourbucket/your/step/location/blog_HBase_graceful_decommission.sh move_regions your-secret-id ip-172-0-0-1.us-west-2.compute.internal s3://yourbucket/yourpath/
Action on failure:Continue

In the HBase web UI, the target region server will serve 0 regions after the evacuation, as shown in the following screenshot.

After that, the stop_RS_IC function in the script stopped the HBase region server and instance controller process on the decommission target after making sure that there is no running YARN container on that node.

Note that the script is for Amazon EMR 5.30.0 and later release versions. For Amazon EMR 4.x-5.29.0 release versions, stop_RS_IC in the script needs to be updated by referring to How do I restart a service in Amazon EMR? In the AWS Knowledge Center. Also, in Amazon EMR versions earlier than 5.30.0, Amazon EMR uses a service nanny to watch the status of other processes. If a service nanny automatically restarts the instance controller, please stop the service nanny using the stop_RS_IC function before stopping the instance controller on that node. Here’s an example:

if [ "\$runningContainers" -eq 0 ]; then
        echo "0 container is running on \${targetRS}" | tee -a /tmp/graceful_stop.log;
        echo "Shutdown IC" | tee -a /tmp/graceful_stop.log;
        sudo /etc/init.d/service-nanny stop | tee -a /tmp/graceful_stop.log;
        sudo /etc/init.d/instance-controller stop | tee -a /tmp/graceful_stop.log;
        sudo /etc/init.d/instance-controller status | tee -a /tmp/graceful_stop.log;
else
        echo "Still have \${runningContainers} containers running on \${targetRS}" | tee -a /tmp/graceful_stop.log;
     	echo "Not to shutdown IC" | tee -a /tmp/graceful_stop.log;
fi

After the step is successfully completed, scale in and define (current core node amount is −1) as the desired target node amount using the Amazon EMR console. Amazon EMR might pick up the target core node to decommission it because the instance controller isn’t running on that node. There can be a few minutes of delay for Amazon EMR to detect the heartbeat loss of that target node through polling the instance controller. Thus, make sure the workload is very low and there will be no container to the target node for a while.

Stopping the instance controller merely increases the decommissioning priority. But method 1 doesn’t guarantee that the target core node will be picked up as the decommissioning target by Amazon EMR. If Amazon EMR doesn’t pick up the decommission target as the decommissioning victim after using method 1, administrators can stop the resize activity using the AWS Management Console. Then, proceed to method 2.

Method 2: Manually decommission the target core nodes

Administrators can terminate the node using the EC2InstanceIdsToTerminate option in the modify-instance-groups API. But this action will directly terminate the EC2 instance and will risk losing HDFS blocks. To mitigate the risk of having a data loss, administrators can use the following steps in off-peak hours with zero or very few running jobs.

First, run the move_hregions function through blog_HBase_graceful_decommission.sh as an Amazon EMR step in method 1. The function moves HRegions to other region servers and stopped the HBase region server as well as the instance controller process.

Then, run the terminate_ec2 function in blog_HBase_graceful_decommission.sh as an Amazon EMR step. To run this function successfully, please provide the target instance group ID and target instance ID to the script. This function merely terminates one node at a time by specifying the EC2InstanceIdsToTerminate option in the modify-instance-groups API. This makes sure that the core nodes are not terminated back-to-back and lowered the risks of missing HDFS blocks. It inspects HDFS and makes sure all HDFS blocks had at least two copies. If an HDFS block have only one copy, the script will exit with an error message similar to, “Some HDFS blocks have only 1 copy. Please increase HDFS replication factor through the following command for existing HDFS blocks.”

$ hdfs dfs -setrep -R -w 2 <the-file-or-directory-you-want-to-modify>

To make sure all upcoming HDFS blocks have at least two copies, reconfigure the core instance group with the following software configuration:

[{
    "classification": "hdfs-site",
    "properties": {
        "dfs.replication": "2"
    },
    "configurations": []
}]

In addition, the terminateEC2 function compares the metadata of the replicating blocks before and after terminating the core node using hdfs dfsadmin -report. This makes sure no under-replicating, corrupted, or missing HDFS block increased.

The terminateEC2 function tracked decommission status. The script will complete after the decommission completes. It can take some time to recover HDFS blocks. The elapsed time depends on several factors such as the total number of blocks, I/O, bandwidth, HDFS handler amount, and name node resources. If there are many HDFS blocks to be recovered, it may take a few hours to complete. Before running the script, please make sure that the instance profile, EMR_EC2_DefaultRole, have permission of elasticmapreduce:ModifyInstanceGroups.

The following is the syntax to use the script to invoke the terminate_ec2 function through blog_HBase_graceful_decommission.sh as an Amazon EMR step:

Step type: Custom JAR
Name: Terminate EC2
JAR location :s3://<region>.elasticmapreduce/libs/script-runner/script-runner.jar
Main class :None
Arguments :s3://yourbucket/your/step/location/blog_HBase_graceful_decommission.sh terminate_ec2 <your-secret-id> <instance_groupID> <target_EC2_Instance_ID>
Action on failure:Continue

Here’s an Amazon EMR step example to move regions:

Step type: Custom JAR
Name: Terminate EC2
JAR location :s3://us-west-2.elasticmapreduce/libs/script-runner/script-runner.jar
Main class :None
Arguments :s3://yourbucket/your/step/location/blog_HBase_graceful_decommission.sh terminate_ec2 your-secret-id ig-ABCDEFGH12345 i-1234567890abcdef
Action on failure:Continue

While invoking terminate_ec2, the script checks HDFS Name Node Web UI for the decommission target to understand how many blocks need to be recovered on other nodes after submitting the decommission request. Here are the steps:

  1. On the Amazon EMR console, version 6.x, find HDFS NameNode web UI. For example, enter http://<master-node-public-DNS>:9870
  2. On the top menu bar, choose Datanodes
  3. In the In operation section, check the on-service data nodes and the total number of data blocks on the nodes, as shown in the following screenshot.
  4. To view the HDFS decommissioning progress, go to Overview, as shown in the following screenshot.

On the Datanodes page, the decommission target node will not have a green checkmark, and the node will be in the Decommissioning section, as shown in the following screenshot.

The step’s STDOUT also reveals the decommission status:

Hostname: ip-172-31-4-197.us-west-2.compute.internal
Decommission Status : Decommission in progress

The decommission target will transit from Decommissioning to Decommissioned in the HDFS NameNode web UI, as shown in the following screenshot.

The decommissioned target will appear in the Dead datanodes section in the step’s STDOUT after the process is completed:

Dead datanodes (1):
Name: 172.31.4.197:50010 (ip-172-31-4-197.us-west-2.compute.internal)
Hostname: ip-172-31-4-197.us-west-2.compute.internal
Decommission Status : Decommissioned
Configured Capacity: 62245027840 (57.97 GB)
DFS Used: 394412032 (376.14 MB)
Non DFS Used: 0 (0 B)
DFS Remaining: 61179640063 (56.98 GB)
DFS Used%: 0.63%
DFS Remaining%: 98.29%
Configured Cache Capacity: 0 (0 B)
Cache Used: 0 (0 B)
Cache Remaining: 0 (0 B)
Cache Used%: 100.00%
Cache Remaining%: 0.00%
Xceivers: 0
Last contact: Tue Jan 14 06:09:17 UTC 2025

After the target node is decommissioned, the hdfs dfsadmin report will be displayed in the last section in the step’s STDOUT . There should be no difference between rep_blocks_${beforeDate} and rep_blocks_${afterDate} as described in the script. It means no additional amount of under-replicated, missing, or corrupt blocks after the decommission. In HBase web UI, the decommissioned region server will be moved to dead region servers. The dead region server records will be reset after restarting HMaster during routine maintenance.

After the Amazon EMR step is completed without errors, please repeat the preceding steps to decommission the next target core node because administrators may have more than one core nodes to decommission.

After administrators complete all decommission tasks, administrators can manually enable the HBase balancer through the HBase shell again:

$ echo "balance_switch true" | sudo -u hbase hbase shell
## To make sure balance_switch is enabled, submit the same command again. The output should say it’s already in “true” status.
$ echo "balance_switch true" | sudo -u hbase hbase shell

Prevent Amazon EMR from provisioning HBase region servers on task nodes

For new clusters, configure HBase settings for master and core groups only and keep the HBase settings empty when launching an Amazon EMR HBase on an S3 cluster. This prevents provisioning HBase region servers on task nodes.

For example, define configurations for applications other than HBase settings in the software configuration textbox in the Software settings section on the Amazon EMR console, as shown in the following screenshot.

Image 007

Then, configure HBase settings in Node configuration – optional for each instance group in the Cluster configuration – required section, as shown in the following screenshot.

Image 008

For master and core instance groups, HBase configurations will be like the following screenshot.

Image 009

Here’s a json formatted example:

[
    {
        "Classification": "hbase",
        "Properties": {
            "hbase.emr.storageMode": "s3"
         }
    },
    {
        "Classification": "hbase-site",
        "Properties": {
            "hbase.rootdir": "s3://my/HBase/on/S3/RootDir/"
        }
    }
]

For task instance groups, there will be no HBase configuration, as shown in the following screenshot.

Image 010

Here’s a json formatted example:

[]

Here’s an example in AWS CLI:

$ aws emr create-cluster \
--applications Name=Hadoop Name=HBase Name=ZooKeeper \
... (skip) \
--instance-groups '[ {"InstanceCount":1,"EbsConfiguration":{"EbsBlockDeviceConfigs":[{"VolumeSpecification":{"SizeInGB":32,"VolumeType":"gp2"},"VolumesPerInstance":2}]},"InstanceGroupType":"MASTER","InstanceType":"m5.xlarge","Configurations":[{"Classification":"hbase","Properties":{"hbase.emr.storageMode":"s3"}},{"Classification":"hbase-site","Properties":{"hbase.rootdir":"s3://my/HBase/on/S3/RootDir/"}}],"Name":"Master - 1"},\
{"InstanceCount":1,"EbsConfiguration":{"EbsBlockDeviceConfigs":[{"VolumeSpecification":{"SizeInGB":32,"VolumeType":"gp2"},"VolumesPerInstance":2}]},"InstanceGroupType":"TASK","InstanceType":"m5.xlarge","Name":"Task - 3"},\
{"InstanceCount":2,"EbsConfiguration":{"EbsBlockDeviceConfigs":[{"VolumeSpecification":{"SizeInGB":64,"VolumeType":"gp2"},"VolumesPerInstance":1}],"EbsOptimized":true},"InstanceGroupType":"CORE","InstanceType":"m5.2xlarge","Configurations":[{"Classification":"hbase","Properties":{"hbase.emr.storageMode":"s3"}},{"Classification":"hbase-site","Properties":{"hbase.rootdir":"s3://my/HBase/on/S3/RootDir/"}}],"Name":"Core - 2"}]' --configurations '[{"Classification":"hdfs-site","Properties":{"dfs.replication":"2"}}]' \
--auto-scaling-role Amazon EMR_AutoScaling_DefaultRole \
... (skip) \
--scale-down-behavior TERMINATE_AT_TASK_COMPLETION --region us-west-2

Stop decommission the HBase region servers on task nodes

For an existing Amazon EMR HBase on an S3 cluster, pass stop_and_check_task_rs to blog_HBase_graceful_decommission.sh as an Amazon EMR step to stop HBase region servers on nodes in a task instance group. The script requirs a task instance group ID and an S3 location to place sharing scripts for task nodes.

The following is the syntax to pass stop_and_check_task_rs to blog_HBase_graceful_decommission.sh as an Amazon EMR step:

Step type: Custom JAR
Name: Stop Hbase Region servers on Task Nodes
JAR location: s3://<region>.elasticmapreduce/libs/script-runner/script-runner.jar
Arguments: s3://yourbucket/your/step/location/blog_HBase_graceful_decommission.sh stop_and_check_task_rs <your-secret-id> <instance_groupID> <S3Path: S3 location>
Action on failure:Continue

Here’s an Amazon EMR step example to stop HBase regions on nodes in a task group:

Step type: Custom JAR
Name: Stop Hbase Region servers on Task Nodes
JAR location :s3://us-west-2.elasticmapreduce/libs/script-runner/script-runner.jar
Main class :None
Arguments :s3://yourbucket/your/step/location/ blog_HBase_graceful_decommission.sh your-secret-id stop_and_check_task_rs ig-ABCDEFGH12345 s3://yourbucket/yourpath/
Action on failure:Continue

This step above not only stops HBase region servers on existing task nodes. To avoid provisioning HBase region servers on new task nodes, the script also reconfigures and scales in the task group. Here are the steps:

  1. Using the move_regions function, in blog_HBase_graceful_decommission.sh, move HRegions on the task group to other nodes and stop region servers on those task nodes.

After making sure that the HBase region servers are stopped at these task nodes, the script reconfigures the task instance group. The reconfiguration details are to let HBase rootdir point to a non-existing location. These settings only apply to the task group. Here’s an example:

[
    {
        "Classification": "hbase-site",
        "Properties": {
            "hbase.rootdir": "hdfs://non/existing/location"
        }
    },
    {
        "Classification": "hbase",
        "Properties": {
            "hbase.emr.storageMode": "hdfs"
        }
    }
]

When the task group’s state returns to RUNNING, the script scales in these task nodes to 0. New task nodes in the upcoming scaling out events will not run HBase region servers.

Conclusion

These scaling steps demonstrate how to handle Amazon EMR HBase scaling gracefully. The functions in the script can help administrators to resolve problems when companies want to gracefully scale the Amazon EMR HBase on S3 clusters without Amazon EMR WAL.

If you have a similar request to scale in an Amazon EMR HBase on an S3 cluster gracefully because the cluster doesn’t enable Amazon EMR WAL, you can refer to this post. Please test the steps in the testing environment for verifications first. After you confirm the steps can meet your production requirements, you can proceed and apply the steps to production environment.


About the Authors

Image 011Yu-Ting Su is a Sr. Hadoop Systems Engineer at Amazon Web Services (AWS). Her expertise is in Amazon EMR and Amazon OpenSearch Service. She’s passionate about distributing computation and helping people to bring their ideas to life.

Image 012Hsing-Han Wang is a Cloud Support Engineer at Amazon Web Services (AWS). He focuses on Amazon EMR and AWS Lambda. Outside of work, he enjoys hiking and jogging, and he is also an Eorzean.

Image 013Cheng Wang is a Technical Account Manager at AWS who has over 10 years of industry experience, focusing on enterprise service support, data analysis, and business intelligence solutions.

Chris Li is an Enterprise Support manager at AWS. He leads a team of Technical Account Managers to solve complex customer problems and implement well-structured solutions.

Има ли бизнес в минералните води?

Post Syndicated from Иво Анев original https://www.toest.bg/ima-li-biznes-v-mineralnite-vodi/

Има ли бизнес в минералните води?

Пили ли сте минерална вода? По всяка вероятност – да. Затова интуитивно си мислим, че знаем какво представлява тя. Съществуват обаче множество определения за минералната вода. От практическа гледна точка най-важното, което е добре да знаем, е, че тази вода:

  • е подземна, с дълбоко залягане (намира се под водонепроницаем слой); 
  • има повишена температура и/или минерален състав;
  • е определена от закона като такава.

Какво съдържат минералните води?

Икономически най-ценният състав на минералните води може да се раздели на различни компоненти:

  • Термален (топлинен). Това е енергията, съдържаща се във водата, която може да бъде използвана в зависимост от температурата за производство на електрическа енергия, отопление и др.
  • Воден. Това е чисто водното съдържание, което може да се използва за бутилиране, спа и балнеологични процедури, поливни дейности и др.
  • Минерален, химичен (вкл. газово съдържание) и биологичен. Именно това е отличителният състав на минералната вода, от който зависят уникалността и качествата ѝ. Този компонент може да се използва за производство на козметика и е важна част от качествата на бутилираната вода и от спецификите на спа процедурите, които се провеждат с нея. Но може да възникнат и проблеми. Например голямото минерално съдържание може да доведе до значително увеличени разходи за инфраструктурна поддръжка. Наднорменото съдържание на арсен, уран и други опасни вещества води до невъзможност водата да бъде използвана за питейни, а в някои случаи и за спа и балнеологични нужди. 

Каква е цената на минералните води?

Цените, имащи отношение към минералните води, се определят от Тарифата за таксите за водовземане, за ползване на воден обект и за замърсяване от 16 юли 2019 г. Тя постановява таксите за извличането им в зависимост от целта на използване и температурата на водата.

За находищата на минерални води, предоставени за управление на общините, съответните общински съвети имат право да определят свои такси, които обаче не могат да бъдат по-ниски от посочените в националната тарифа. Община Карлово например е приела тарифа, съответстваща на националната, с единични размери на таксите, вариращи в зависимост от целта на използване и температурата на водата.

Цената на минералната вода се определя от Министерството на околната среда и водите. В зависимост от температурата, таксата за използването за битови и питейни нужди варира между 0,031 и 0,29 лв. за кубичен метър. За болниците за лечение и рехабилитация таксата е между 0,04 и 0,05 лв./м³, за всички други цели – между 0,15 и 0,5 лв./м³.

Тези такси значително отстъпват дори от цената на водата, която може да бъде закупена от водопроводната мрежа. Например „Софийска вода“ доставя питейна вода в Столичната община за 2,194 лв./м³ с ДДС, като общата цена заедно с отвеждането и пречистването на отпадни води достига 3,695 лв./м³ с ДДС.

Това означава, че цената на кубичен метър минерална вода е между 71 и 4,4 пъти по-ниска, отколкото на водата, доставяна по водопроводната мрежа. И то дори без да се отчита, че термалните минерални води притежават също значителна топлинна енергия, понякога надхвърляща стойността на водата.

Каква е същинската стойност на минералната вода?

Нека се опитаме да пресметнем каква би била истинската стойност на минералната вода. За основа може да вземем например стойността на водата, предоставена за ползване на Столичната община. Нейният дебит е 83,49 л/сек. За да можете да си представите за какво количество става въпрос, това е малко повече от водата, която тече в Перловска река в Южния парк през лятото.

Има ли бизнес в минералните води?
© Иво Анев

Обемът на минералната вода за една година, предоставена на Столичната община, е 2,633 млрд. л. Ако приравним закупуването на тези количества за една година с цената на водата от водопроводната мрежа, без да добавяме разходите за отвеждане и пречистване, ще получим, че еквивалентната цена на тази вода за една година е 5,774 млн. лв.

Средната (претеглена) температура на всички източници на минерална вода, предоставени на Столичната община, е 35,75°C. Топлинната енергия във водата (пресметната като разлика със средната температура на водата от водопроводната мрежа, която е 14°C) е еквивалентна на 67 073 623 киловата годишно, или 67,07 гигавата. 

Средната цена на електроенергията за крайни потребители на „Електрохолд“ е 0,282 лв./кВтч. Следователно годишната цена за загряване на това количество вода без загуби би била 18,915 млн. лв.

Ако направим консервативна сметка – дори без да отчитаме допълнителната стойност на полезните вещества в състава на водата, – можем да установим, че става въпрос за ресурс на стойност 24,689 млн. лв. годишно, от който се използва много малка част – около 3 л/сек.

Привлекателната сила на минералната вода

Минералните води са силно привлекателни. Това ясно се вижда, когато сравним спа курорта Карлови Вари и целия Южноморавски регион в Чехия. Карлови Вари се простира на площ от 59,08 кв.км, а населението му е малко под 50 000 души. Южноморавският регион заема площ от 7188 кв. км, а населението му е над 1,2 млн. души. Карлови Вари обаче привлича 1 390 000 туристи годишно, докато целият Южноморавски регион – едва 830 000.

Каква е причината? И на двете места има красиви замъци, а в Южноморавския район има значително повече природни дадености, с изключение на минерални води.

Какво обаче привлича туристите толкова много към Карлови Вари? Можем да твърдим, че това е именно минералната вода. На този красноречив пример може да се противопостави Прага, която въпреки липсата на минерална вода е посетена от 7,44 млн. туристи през 2023 г. Прага обаче е европейска столица с население 1,335 млн. жители и с несравнимо по-голяма икономика от Карлови Вари. Освен това туристическите посещения в балнеокурорта, съотнесени към населението, са 5 пъти повече.

Наличието на впечатляващи сгради, казина и курортни дейности в Карлови Вари, за които можем да твърдим, че са привлекателни за туристите, са следствие от наличието на термални минерални води.

Има ли бизнес в минералните води?
Минералната баня в Банкя. © Иво Анев

Въпреки липсата на достатъчно данни, същата зависимост наблюдаваме и в България – местата с наличие на термални минерални води в общия случай привличат повече туристи и икономически се развиват по-добре, отколкото места с аналогични дадености, но без минерална вода. Например град Сандански, известен със своите минерални води, не само привлича повече туристи, но е икономически по-силен от традиционния център на района – град Петрич, а от 2024 г. има и по-голямо население. Най-популярният ни зимен курорт – Банско, разполага с минерална вода, както и най-популярният летен – Слънчев бряг.

Преки и косвени приходи от минералните води

Безусловно най-големи преки приходи от минерална вода се получават от нейното бутилиране. Нека направим следния мисловен експеримент. Започваме да бутилираме водата от Централната минерална баня при среден размер на бутилката 1 литър и печалба 0,05 лв. При пълна продажба на бутилираната вода директната ни печалба ще е 20,183 млн. лв.

Бутилирането обаче унищожава възможността за косвени приходи. Известен факт е, че директното ползване на термална минерална вода често не води до големи приходи, а още по-малко до печалби. Именно затова около местата за отдих и възстановяване навсякъде по света винаги са се изграждали ресторанти, козметична индустрия, казина, опери и др., които се възползват от привлекателната сила на водата. Град Баден-Баден в Германия например разполага с минерална вода, чийто дебит е малко над 9 л/сек, но брутният вътрешен продукт (БВП) на глава от населението е 52 234 евро, което надхвърля регионалния – 50 982 евро, а още повече средния за Германия – 49 525 евро, въпреки относителната откъснатост на курорта от големите икономически центрове. Това се дължи именно на всички допълнителни услуги, свързани с минералната вода, които подпомагат икономическото развитие. 

Подобни примери има и в други курорти, села и градове, разполагащи с термална минерална вода – от Виши във Франция до Сареин в Иран.

Изчислението на косвените ползи от минералните води е сложна задача, тъй като зависи от огромно количество променящи се фактори. Наличието им обаче е очевидно и неотменимо и от гледна точка на БВП, и от гледна точка на допълнителните заведения и забавления, които често се изграждат около и на местата, където има термални минерални води. Маркетингът на съответната минерална вода и на допълнителните (косвени) услуги, както и достъпността са от ключово значение за успеха.

Термалната минерална вода е привлекателна за хората, съответно е и двигател на икономиката и туризма. Използването ѝ може да максимизира нейната полезност при правилно разпределение на ресурсите там, където могат да бъдат най-нужни за гражданите и туристите. Търсенето единствено на директни печалби от минералната вода показва липсата на разбиране за нейната притегателна сила и за големия потенциал за привличане на косвени приходи.

Бизнес в минералните води има, но са необходими и инвестиции, и мисъл.


В настоящата ни съвместна поредица с „Екипът на София“ обсъждаме планирането, озеленяването, архитектурата, инфраструктурата, мобилността и още много други градски теми, описваме добрите примери и търсим възможните решения за подобряването на качеството на живот в нашите градове. 

Има ли бизнес в минералните води?


The collective thoughts of the interwebz