You’re building a data agent that lets business users ask questions about lakehouse data in natural language. You’ve already built governance policies that control who can access which datasets. The challenge is making the agent respect those rules without rebuilding them in your application code.
When a user asks a question, the agent maps it to data and constructs a query. The tool runs under its own AWS Identity and Access Management (IAM) role, so AWS Lake Formation sees the tool’s credentials, not the person behind the request. This leaves you with two inadequate options: restrict tool access (limiting self-service analytics) or rebuild access controls in application code (moving governance out of the data layer).
In this post, we show you a different approach: identity-aware AI data agents that propagate each user’s identity through every hop, from the user, through the agent, into the tool, so Lake Formation evaluates the user’s grants. Your application code makes no authorization decisions, existing Lake Formation policies work without modifications, and AWS CloudTrail records the actual person who accessed the data.
In this post, you learn how to:
Set up per-user data access controls for AI agents querying your lakehouse without rewriting your existing Lake Formation governance policies by configuring Amazon Bedrock AgentCore to carry each user’s identity through trusted identity propagation (TIP).
Ensure auditability and compliance by performing a server-side token exchange inside AWS Lambda that converts the identity token into Lake Formation credentials scoped to the real user, with CloudTrail recording every query.
Validate the pattern end-to-end by testing with multiple users and confirming per-user query results and CloudTrail audit evidence.
The building blocks in this post, OAuth 2.0 token delegation, AWS IAM Identity Center, Lake Formation, and Lambda are well-documented individually. The new constraint is that a foundation model (FM) now sits in the middle of the propagation chain. The FM is the agent’s brain, it decides which tools to call and what arguments to pass and anything that enters its context (prompts, tool schemas, arguments) is accessible within that trust boundary. So, the user’s identity token must reach the tool, but it must do so on the HTTP transport layer, bypassing the FM’s reasoning layer entirely. This post demonstrates the three Amazon Bedrock AgentCore configurations that achieve that.
Whether you’re building agents on Strands, LangGraph, or a similar framework, this post gives you a deployable pattern on Amazon Bedrock AgentCore. Security engineers will find the identity-transport and audit properties relevant, and data platform owners will see how existing Lake Formation grants extend to AI workloads with no changes.
With this pattern (shown in Figure 1), your data agent can query Lake Formation governed data with per-user access controls, full CloudTrail audit trails, and no changes to your existing governance policies. Here’s how it works.
Two tokens travel through the system. An access_token authenticates the request at each trust boundary (Bedrock AgentCore Runtime, Bedrock AgentCore Gateway). An id_token carries your identity and is exchanged, server-side, for the identity context that Lake Formation evaluates.
A separate TIP role carries only the IAM permissions needed to call service APIs, it has no Lake Formation data grants.
Lake Formation evaluates only the propagated user identity, not the TIP role.
The request flow is:
User to UI: The user authenticates with an OpenID Connect (OIDC) identity provider (IdP). This post uses Amazon Cognito, but you can use any OIDC provider, such as Okta. The UI receives an id_token and an access_token.
UI to Bedrock AgentCore Runtime: The UI calls the agent running in AgentCore Runtime over HTTPS. The access_token goes in the standard Authorization header. The id_token goes in a custom header: X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken. The HTTP body contains only the user’s prompt.
AgentCore Runtime to agent code: The runtime validates the access_token against the configured JSON Web Token (JWT) authorizer, then passes the request to the agent container with both headers accessible through context.request_headers.
Agent to Bedrock AgentCore Gateway: The agent opens a Model Context Protocol (MCP) connection to an AgentCore gateway, including both headers on the connection. The AgentCore gateway validates the access_token and forwards the custom header to its Lambda target.
AgentCore Gateway to Lambda: The propagated headers arrive in context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’].
Lambda to the data layer: Lambda validates the id_token, exchanges it for an identity context, assumes a role with that context, and runs the Amazon Athena query under the user’s identity.
Lake Formation evaluates grants against the real user. Athena returns only the rows and columns that the user is entitled to see. CloudTrail records the assumed role with an onBehalfOf entry identifying the human.
Now that you’ve seen the end-to-end flow, the following sections walk through each piece, starting with what you need to have in place before you build.
Prerequisites
This post assumes you have the working knowledge of OAuth 2.0, IAM, and Lake Formation grants.
An OIDC IdP. The reference implementation uses Amazon Cognito as the demo IdP, but the pattern is IdP-agnostic. Auth0, Microsoft Entra ID, Okta, Ping, or any OIDC-compliant provider works identically, if your TTI accepts its tokens.
This post doesn’t walk through setting up any of these components. The existing AWS documentation covers each one. For more information, see the links in the preceding list and the related resources at the end of this post.
The three Bedrock AgentCore configuration steps
Three Bedrock AgentCore features make this pattern work. Together they form the chain of custody for the user’s id_token from the moment it arrives at the Bedrock AgentCore Runtime to the moment Lambda uses it.
Configure the runtime request header allow list
Bedrock AgentCore Runtime doesn’t pass request headers into the agent container by default. You opt in by declaring an allow list, either through agentcore configure or directly in the runtime configuration:
AgentCore Runtime supports two types of forwarded headers:
The standard Authorization header for OAuth inbound JWT authentication (access_token), and
Custom headers prefixed with X-Amzn-Bedrock-AgentCore-Runtime-Custom-
The id_token in this pattern uses a custom header. Inside the agent, the allow listed headers arrive as a dictionary object on the request context.
The following Python code runs in the agent container:
from bedrock_agentcore.runtime import BedrockAgentCoreApp

ID_TOKEN_HEADER = "X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken"
app = BedrockAgentCoreApp()

@app.entrypoint
def invoke(payload, context):
    request_headers = getattr(context, "request_headers", None) or {}

    id_token = ""
    access_token = ""
    for key, value in request_headers.items():
        if key.lower() == ID_TOKEN_HEADER.lower():
            id_token = value
        elif key.lower() == "authorization":
            access_token = value.replace("Bearer ", "")

    # ... build MCP headers and call the Gateway
The agent code reads the id_token from the HTTP transport and forwards it (also on the HTTP transport) to the next hop. It doesn’t treat the token as a tool argument and doesn’t inject it into a prompt.
Key takeaway: The runtime allow list is the first gate. Without it, the id_token doesn’t reach your agent code.
Configure AgentCore Gateway metadata for header propagation
An AgentCore Gateway is the Model Context Protocol (MCP) endpoint the agent talks to. When AgentCore Gateway invokes a Lambda target, it doesn’t forward arbitrary request headers by default. You configure which headers to propagate using metadataConfiguration.allowedRequestHeaders on the target:
Notice that the tool schema doesn’t include an id_token parameter; there’s no token parameter on any tool. The FM doesn’t see, select, or pass an id_token because the token isn’t part of the tool’s contract. It travels parallel to the tool call, on the HTTP connection, through metadataConfiguration.
This is a critical property for security. If you put the id_token in the tool schema instead, the FM becomes responsible for passing it, which means the token lands in prompts, traces, memory, and logs. Keeping the token off the tool contract keeps it out of the FM entirely.
Key takeaway: The metadataConfiguration of the AgentCore gateway is the second gate. It controls which headers cross from the agent into the Lambda function without touching the tool schema.
Read propagated headers in Lambda
On the Lambda side, the propagated header arrives not in the event body but in the client context, under a specific key.
The following Python code runs in the Lambda function:
ID_TOKEN_HEADER = "X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken"

def lambda_handler(event, context):
    client_ctx = getattr(context.client_context, "custom", {}) or {}
    propagated_headers = client_ctx.get("bedrockAgentCorePropagatedHeaders", {})
    id_token = propagated_headers.get(ID_TOKEN_HEADER)

    if not id_token:
        return {"statusCode": 400, "body": {"error": "missing id_token"}}

    # Tool arguments from the agent's call (no id_token here)
    query = event["query"]
    database = event["database"]
    workgroup = event["workgroup"]
    output_location = event["output_location"]

    # ... validate token, exchange, run query
The event dictionary contains the tool’s declared parameters and nothing else. You reach the id_token only through context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’]. That’s the handoff point.
Key takeaway: The id_token arrives through the client context rather than tool arguments; the FM has no access to it. The Lambda is the only component that reads the token.
Perform the server-side token exchange
After Lambda has the id_token, it validates the token and exchanges it for an identityContext. This step uses standard IAM Identity Center TIP mechanics. That it happens inside Lambda rather than anywhere else is what keeps the identity context from crossing a process boundary.
The identityContext is created and consumed inside a single Lambda invocation. It doesn’t get returned to the agent, the gateway, or the UI.
The resulting boto3.Session holds short-lived credentials whose underlying identity assertion is the real user. When the session calls Athena, the query runs with the user’s identity propagated. Lake Formation sees the user, not the Lambda function’s role.
Everything after this, including the Athena query and result formatting, is standard boto3.
Configure Lake Formation grants
You need one grant to the IAM Identity Center user or group. That’s the whole story at the Lake Formation layer.
This is the grant Lake Formation evaluates at query time. You add column-level and row-level filters to the same user or group the same way. Nothing here is aware of or specific to AI agents. If you already have a Lake Formation grants model for human users, you already have the grants this pattern needs.
Understanding the TIP role: The TIP role that Lambda assumes has no Lake Formation data grants. It holds only IAM permissions to call the service APIs: athena:* for query runs, glue:* for catalog reads, lakeformation:GetDataAccess for the query plan handshake, and Amazon S3 access for the Athena output bucket. When Lambda assumes this role with an identityContext attached through ProvidedContexts, Lake Formation evaluates only the propagated user identity against its grants. The role itself is transparent to the authorization decision.
In the more common agent runs as a role pattern, the role carries the grants, which is why per-user governance breaks. Here the role carries no grants; it’s a session vehicle, not an authorization subject.
Test the pattern end-to-end
Two users, same question, different outcomes.
User A has SELECT on trip_details. They ask the agent for five records from the table.
Figure 2: Five records are requested and returned by the agent
User B has no grant on trip_details. They ask the same question.
Figure 3: User doesn’t have access to the data
No code changed between the two interactions. No parameter was toggled. Lake Formation made the decision based on the propagated identity.
The CloudTrail record for the AssumeRole call shows the delegation:
The onBehalfOf block closes the audit loop. Each query the agent runs on a user’s behalf has a CloudTrail record naming that user, with no additional instrumentation in your code.
Security properties
Four properties follow from this architecture. These are the core value propositions of the identity-aware pattern:
The id_token never reaches the foundation model: It travels on HTTP headers at every hop, and Lambda reads it from context.client_context.custom. It’s not a parameter on any tool. The FM has no path to it: not in tool arguments, not in prompts, not in memory, not in traces.
The identity context stays inside a single Lambda invocation: It’s derived from the id_token, used immediately in an AssumeRole call, and discarded. It doesn’t go back to the agent, the gateway, or the UI.
Authorization decisions live in Lake Formation, against the real user only: The TIP role the Lambda function assumes has no data grants. Lake Formation evaluates the propagated user identity. No code path in the agent, gateway, or Lambda function performs authorization logic.
The audit trail requires no extra work: The CloudTrail AssumeRole event with onBehalfOf identifies the human user for every query. You get the same audit fidelity you would have for human users accessing data directly.
Deploy the pattern
To deploy this pattern, you need to configure four things:
An OIDC IdP with a TTI in IAM Identity Center accepting its tokens, and an Identity Center OAuth Application configured for CreateTokenWithIAM.
Bedrock AgentCore Runtime running your agent container with requestHeaderAllowlist covering Authorization and your custom id_token header.
Bedrock AgentCore Gateway with a Lambda target whose metadataConfiguration.allowedRequestHeaders includes the id_token header. The Lambda target’s tool schema has no id_token parameter.
Lambda reading the id_token from context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’], performing the token exchange through sso-oidc:CreateTokenWithIAM, and calling sts:AssumeRole with ProvidedContexts to get the TIP-bearing session.
Conclusion
When an AI agent queries a governed lakehouse, the data layer needs to know who’s asking, not which role the agent is running under. This post showed you how to resolve that by treating the agent as an OAuth delegated actor. The user’s token travels alongside the agent’s HTTP transport but doesn’t enter the model’s context, and the token exchange that produces query-time credentials happens server-side inside Lambda, scoped to a single invocation.
The three Bedrock AgentCore features that make this composable (requestHeaderAllowlist on runtime, metadataConfiguration.allowedRequestHeaders on gateway, and bedrockAgentCorePropagatedHeaders on Lambda) are specific to building on Bedrock AgentCore. Everything downstream of Lambda is IAM Identity Center and Lake Formation functionality.
If you’re building agents that read governed data, you don’t have to choose between a single over-permissioned service role and per-user code paths. The identity the data layer evaluates can be the real user, the audit trail can name the real user, and the foundation model doesn’t need to know the user’s token exists.
The result is a clean separation: the user’s identity travels end-to-end, the model never sees it, and the data layer enforces it exactly as if the user queried directly.
You can now use AWS IAM Identity Center authentication with enhanced VPC routing on Amazon Redshift clusters and Amazon Redshift Serverless workgroups. Your users get single sign-on with their existing corporate credentials, and the authentication traffic originates from within your virtual private cloud (VPC) through a VPC endpoint, staying on the AWS private network.
Many organizations also require that this traffic doesn’t traverse the public internet. Enhanced VPC routing sends everything between your cluster and other AWS services through your VPC, where you can govern it with security groups, network ACLs, and endpoint policies, and observe it in VPC Flow Logs. For teams with data residency, regulatory, or network isolation requirements, it’s often mandatory.
In this post, we show how the new IAM Identity Center VPC endpoints provide a private network path for authentication traffic when enhanced VPC routing is enabled. We walk through the endpoint setup and validate the flow from Query Editor V2 and a SQL client. To use this feature, your Amazon Redshift cluster must be running patch 204 or later, and you must create the VPC endpoints described in the following steps.
Solution overview
When a user signs in with IAM Identity Center from Query Editor V2 or a SQL client, Amazon Redshift doesn’t simply accept the token the client presents. It validates the token with IAM Identity Center and resolves the caller’s identity before the session is established. These calls originate from Amazon Redshift, not from your client, and enhanced VPC routing changes the network path they take.
Authentication flow with enhanced VPC routing
With enhanced VPC routing enabled, the calls Amazon Redshift makes to IAM Identity Center traverse your VPC and follow your networking configuration. The flow is as follows:
The user signs in through Query Editor V2 or a SQL client and authenticates against your identity provider through IAM Identity Center.
IAM Identity Center issues an access token, which the client presents to Amazon Redshift on the database connection.
Amazon Redshift validates the access token against the IAM Identity Center OpenID Connect (OIDC) endpoint, confirming the token’s scopes and the user’s entitlement to the Amazon Redshift application. It doesn’t trust the token the client presented without verification.
Amazon Redshift calls the same OIDC endpoint again to exchange that token for one scoped to Amazon Redshift.
Amazon Redshift calls the IAM Identity Center identity store to resolve the user and their group membership.
Amazon Redshift maps the resolved identity to a database identity, applies role-based access control, and establishes the session.
The following diagram illustrates this authentication flow, showing how each call from Amazon Redshift to IAM Identity Center traverses the VPC through interface endpoints.
Figure 1: IAM Identity Center authentication flow with enhanced VPC routing enabled
As shown in the diagram, steps 3–5 represent calls that Amazon Redshift makes through your VPC to the IAM Identity Center OIDC and identity store endpoints.
Because a cluster with no public IP address doesn’t use an internet gateway route, Amazon Redshift has no path to IAM Identity Center by default. You provide one with interface VPC endpoints for the two services it needs, the IAM Identity Center OIDC endpoint and the identity store endpoint, which keep the traffic on the AWS network over AWS PrivateLink.
This solution covers the following steps:
Enable enhanced VPC routing.
Verify the DNS attributes on your VPC.
Create the interface VPC endpoints required for IAM Identity Center authentication.
Create interface VPC endpoints for AWS Glue and AWS Lake Formation (optional, if you query a data lake or lakehouse).
Create an Amazon Simple Storage Service (Amazon S3) gateway endpoint.
Validate that the endpoints are available and using private DNS.
Test single sign-on with Amazon Redshift Query Editor V2.
Test single sign-on with a SQL client using the Amazon Redshift JDBC driver.
Verify the calls on AWS CloudTrail.
Prerequisites
You should have the following prerequisites:
An AWS account with an Amazon Redshift provisioned cluster. Amazon Redshift Serverless also supports enhanced VPC routing, and the same endpoints apply, but you substitute the equivalent workgroup commands and settings.
A cluster running patch 204 or later, which is the minimum maintenance version that supports IAM Identity Center authentication with enhanced VPC routing.
Permissions to create VPC endpoints in the VPC where the cluster runs, specifically ec2:CreateVpcEndpoint and ec2:DescribeVpcEndpoints.
Optionally, an Amazon Elastic Compute Cloud (Amazon EC2) instance inside the same VPC with SQL Workbench/J and the Amazon Redshift JDBC driver, version 2.1.0.30 or later with its dependent libraries, to test the SQL client flow.
Walkthrough
The examples in this post use the Canada (Central) AWS Region (ca-central-1). Replace all placeholder values with your own.
Step 1: Enable enhanced VPC routing and turn off public access
To control network traffic with Amazon Redshift enhanced VPC routing, you enable enhanced VPC routing in Amazon Redshift. The cluster or workgroup must also not be publicly accessible, so that traffic to IAM Identity Center and other services goes through your VPC endpoints rather than an internet gateway. Follow the instructions in Enable enhanced VPC routing to enable it for a new provisioned cluster or serverless workgroup. For an existing cluster or workgroup, follow these steps:
Open the provisioned cluster or serverless workgroup you want to modify:
For an existing provisioned cluster – choose the Properties tab.
For an existing serverless workgroup – choose the Data access tab.
In the Network and security section, choose Edit.
Select Turn on enhanced VPC routing to route network traffic through the VPC.
If Turn on Publicly accessible is enabled, clear it so the cluster or workgroup is not publicly accessible.
Choose Save changes.
The following screenshot shows the Network and security section with enhanced VPC routing enabled and public accessibility turned off.
Figure 2: Enable enhanced VPC routing in Amazon Redshift
Note: Amazon Redshift restarts the cluster automatically when you change enhanced VPC routing. Make this change during a maintenance window.
Step 2: Verify the DNS attributes on your VPC
Private DNS is what redirects the public AWS service hostnames to your interface endpoints, and it depends on two VPC attributes. Follow these steps:
Navigate to Amazon Redshift and choose the Properties tab for Amazon Redshift provisioned, or the Data access tab for Amazon Redshift Serverless.
Under Network and security setting, choose the associated VPC.
Your VPC details open in a new browser tab.
Review the Details section, where the attributes appear as DNS hostnames and DNS resolution. Make sure that both properties are set to Enabled. The following screenshot shows the VPC Details page with both DNS attributes set to Enabled.
Figure 3: DNS hostnames and DNS resolution enabled on the VPC Details page
If either of the properties is Disabled, choose Actions, choose Edit VPC settings, select Enable on the attribute you need, and choose Save. The following screenshot shows the Edit VPC settings page where you enable these DNS attributes.
Figure 4: Enable DNS hostnames and DNS resolution
Step 3: Create the interface VPC endpoints for IAM Identity Center authentication
Create the two interface endpoints that the authentication flow needs. Each corresponds to one of the two IAM Identity Center calls in the authentication flow described earlier:
Service endpoint
Used for
com.amazonaws.<region>.sso-oauth
Validating and exchanging the IAM Identity Center access token
com.amazonaws.<region>.identitystore
Resolving the user and their group membership
To create an interface endpoint for an AWS service
IAM Identity Center is a Regional service, so these endpoints must reach the AWS Region where your IAM Identity Center instance is available. If you’re using IAM Identity Center multi-Region replication (your instance is replicated to the Region where your Amazon Redshift cluster runs), leave Enable Cross Region endpoint unchecked.
For Service name, search for sso-oauth and select the service for your Region (com.amazonaws.<region>.sso-oauth). The following screenshot shows the top section of the Create endpoint page with the sso-oauth service selected.
Figure 5: Create an interface VPC endpoint, part 1
For VPC, select the VPC from which you will access the AWS service. In our use case, we choose the Amazon Redshift VPC.
To enable private DNS support, select Additional settings and choose Enable private DNS name.
For Subnets, select the subnets in which to create endpoint network interfaces. You can select one subnet per Availability Zone. You can’t select multiple subnets from the same Availability Zone. For more information, see Subnets and Availability Zones.
For IP address type, choose IPv4. This assigns IPv4 addresses to the endpoint network interfaces. This option is supported only if all selected subnets have IPv4 address ranges and the service accepts IPv4 requests.
For Security groups, select the security groups to associate with the endpoint network interfaces. For this post, we have selected default security group associated with Redshift. The following screenshot shows the VPC, subnet, and security group selections for the endpoint.
Figure 6: Create an interface VPC endpoint, part 2
For Policy, to allow all operations by all principals on all resources over the interface endpoint, select Full access. To restrict access, select Custom and enter a policy. This option is available only if the service supports VPC endpoint policies. For more information, see Endpoint policies.
(Optional) To add a tag, choose Add new tag and enter the tag key and the tag value.
Choose Create endpoint. The following screenshot shows the policy and tag settings before you create the endpoint.
Figure 7: Create an interface VPC endpoint, part 3
Repeat steps 1–14 for the identity store endpoint, search for identitystore and select the service for your Region (com.amazonaws.<region>.identitystore).
Two settings in the preceding steps are important:
Enable private DNS name is required. Amazon Redshift resolves the public service hostname, for example, oidc.<region>.amazonaws.com. Private DNS is what points that hostname at your interface endpoint, so the traffic stays inside your VPC.
Use the cluster’s security group, because the cluster is the caller. The endpoint’s security group must allow inbound HTTPS on port 443 from the cluster. Reusing the cluster’s own security group is the simplest approach when it already allows traffic from itself. A dedicated security group needs an explicit port 443 inbound rule from the cluster’s security group.
(Optional) To create an interface endpoint using the command line
Step 4 (optional): Create endpoints for AWS Glue and AWS Lake Formation
Complete this step only if your cluster queries external data through the AWS Glue Data Catalog and AWS Lake Formation. Common examples include Amazon S3 Tables, a capability of Amazon S3, and data lakes registered with Lake Formation. If you only need single sign-on, you can skip to Step 5. Amazon Redshift calls the AWS Glue Data Catalog to enumerate databases and tables, and calls AWS Lake Formation to check permissions and vend temporary credentials for the underlying data. Like the authentication calls, these are made by the cluster, so with enhanced VPC routing enabled they travel through your VPC and need a path of their own.
Repeat steps 1–14 from Step 3 for:
com.amazonaws.<region>.glue.
com.amazonaws.<region>.lakeformation.
With these endpoints in place, Amazon Redshift routes external catalog operations such as listing external tables through the VPC endpoints rather than the public internet, keeping metadata traffic on the AWS network.
Step 5: Create an Amazon S3 gateway endpoint
With enhanced VPC routing enabled, anything the cluster does against Amazon S3 (COPY, UNLOAD, and Amazon S3 Tables) also travels through your VPC. Create a gateway endpoint and associate it with the route table(s) used by your cluster’s subnets:
In the navigation pane, choose Endpoints, then choose Create endpoint.
For Type, choose AWS services.
For Service name, search for s3 and select the service for your Region with Type: Gateway (com.amazonaws.<region>.s3). The following screenshot shows the Create endpoint page with the Amazon S3 gateway service selected.
Figure 8: Create an Amazon S3 gateway endpoint, part 1
For VPC, choose your Amazon Redshift VPC.
For Route tables, select the route table(s) associated with the subnets your cluster runs in.
Choose Create endpoint. The following screenshot shows the VPC and route table selections for the S3 gateway endpoint.
Figure 9: Create an Amazon S3 gateway endpoint, part 2
Step 6: Validate the endpoints
Confirm in the Amazon VPC console that every endpoint you created is available, and that private DNS is enabled on the interface endpoints.
In the endpoints list, use the filter bar to filter by VPC ID (choose VPC ID and select your Amazon Redshift VPC). Then locate the endpoints you created for this walkthrough, sso-oauth, identitystore, the Amazon S3 gateway endpoint, and (if you created them) glue and lakeformation.
Confirm each endpoint shows a Status of Available.
Select each interface endpoint (sso-oauth, identitystore, glue, lakeformation) and, on the Details tab, confirm Private DNS names enabled is Yes. The following screenshot shows the completed endpoints list with each endpoint in the Available state.
Figure 10: VPC endpoints created in this walkthrough, in the Available state
Step 7: Test single sign-on with Amazon Redshift Query Editor V2
On the Amazon Redshift console, choose Query editor v2.
Choose your cluster and then choose IAM Identity Center as the connection method.
Sign in with your corporate credentials when prompted.
Expand the cluster in the tree view to list databases, schemas, and tables.
The database list populates within a few seconds. Confirm the login on the server side by querying the connection log. Run this as a user who does not use IAM Identity Center, for example a database user with a password, or through the Amazon Redshift Data API:
SELECT record_time, user_name, auth_method, driver_version, remote_host, event
FROM sys_connection_log
WHERE auth_method LIKE '%Idc%'
AND record_time > dateadd(minute, -15, getdate())
ORDER BY record_time DESC;
A successful sign-in shows user_name as <idc_namespace>:<[email protected]> with event of authenticated, which confirms that the identity was resolved through the endpoints you created. The following screenshot shows the sys_connection_log query results, where each IAM Identity Center sign-in appears with a user_name in the <idc_namespace>:<[email protected]> format.
Figure 11: Query Editor V2 connected with IAM Identity Center, showing the database list
Step 8: Test single sign-on with a SQL client
Testing from a SQL client on an EC2 instance inside your VPC is the stronger validation, and we recommend doing both. Query Editor V2 connects through an Amazon Redshift managed proxy, so its connections are recorded with a loopback address. A client running inside your VPC connects to the cluster endpoint directly, which is exactly the path the endpoints you created are there to serve.
Set up SQL Workbench/J
SQL Workbench/J connects through the Amazon Redshift JDBC driver. On an EC2 instance in the same VPC as your cluster, download and install SQL Workbench/J.
Download the latest Amazon Redshift JDBC driver together with its dependent libraries, and extract the archive to a folder on the instance.
Start SQL Workbench/J, and choose File, then Manage Drivers.
Choose the Create a new entry icon, and for Name, enter Amazon Redshift.
For Library, choose the folder icon, and select the driver JAR file along with every JAR file in the dependent libraries folder. Keep only one version of the driver in the list, and remove any previous entries.
Choose File, then Connect window, and choose the Create a new connection profile icon. Enter a name for the profile, such as redshift-idc.
For Driver, choose the Amazon Redshift driver that you created.
For URL, enter your cluster endpoint in the form jdbc:redshift://<cluster endpoint>:5439/<database>, for example jdbc:redshift://my-redshift-cluster.abc123xyz789.ca-central-1.redshift.amazonaws.com:5439/dev.
Leave Username and Password empty. The browser plugin obtains the identity interactively.
Choose Extended Properties, and add the following three properties:
The Region of your IAM Identity Center instance, such as ca-central-1
Clear Separate connection per tab, so that each editor tab reuses the same physical connection rather than prompting you to sign in again.
Choose Test. Your default browser opens. Sign in with your corporate credentials, and then choose Allow access so that the Amazon Redshift JDBC driver can access your data.
If the connection succeeds, you see a prompt confirming the connection to your Amazon Redshift endpoint, as shown in the following screenshot.
Figure 12: SQL Workbench/J connection for Amazon Redshift using the IAM Identity Center browser plugin
In the browser, you will see the following message once the authentication is successful.
Congratulations!You have IAM Identity Center single sign-on working on an Amazon Redshift cluster with enhanced VPC routing enabled.
Step 9: Verify the calls on AWS CloudTrail
You can confirm from AWS CloudTrail that these calls travel through your interface endpoints rather than the internet. Each event includes a vpcEndpointId field naming the endpoint the call traversed, along with a vpcEndpointAccountId field identifying the account that owns it.
The following table maps each interface endpoint to the CloudTrail event you’ll see:
The following screenshot shows the snippet from the CloudTrail logs showing the CreateTokenWithIAM event that Amazon Redshift generates when it exchanges the IAM Identity Center access token. The eventSource is sso-oauth.amazonaws.com, and the vpcEndpointId field confirms the call traversed your interface VPC endpoint rather than the public internet. The invokedBy field shows the call originated from Amazon Redshift (redshift.amazonaws.com), not from the client.
Figure 13: CloudTrail CreateTokenWithIAM event traversing the sso-oauth interface endpoint
Similarly, the following screenshot shows a DescribeUser event (event source identitystore.amazonaws.com) generated when Amazon Redshift resolves the authenticated user against the identity store. As with the previous event, the invokedBy field shows the call originated from Amazon Redshift, and the vpcEndpointId field confirms it traversed the identitystore interface endpoint.
Figure 14: CloudTrail DescribeUser event traversing the identitystore interface endpoint
Note: where the events appear depends on how your IAM Identity Center instance is deployed:
CreateTokenWithIAM (event source sso-oauth.amazonaws.com) is recorded in the same account as your Amazon Redshift cluster.
Identity Store API calls (DescribeUser, ListGroupMembershipsForMember, BatchDescribeGroup) are recorded in the account that owns your IAM Identity Center instance. The event source is identitystore.amazonaws.com. If you use a centralized instance in a delegated administrator or management account, these events appear in that account and not in the account running your cluster. Searching the cluster’s own account returns nothing, even when authentication is working normally. To confirm which account to look in, run aws sso-admin list-instances and check OwnerAccountId.
Clean up
To avoid incurring future charges, delete the resources you created for this walkthrough. These endpoints provide the network path for single sign-on while enhanced VPC routing is enabled, so remove them only if you no longer need the integration.
On the Amazon VPC console, choose Endpoints.
Select the sso-oauth and identitystore interface endpoints you created, and choose Actions, then Delete VPC endpoints.
Select the glue and lakeformation interface endpoints, if you created them, and delete them.
Select the Amazon S3 gateway endpoint and delete it. This also removes its route table entries.
Terminate the EC2 instance you used to test the SQL client connection, if you created one for this walkthrough.
If you no longer need the integration, remove the IAM Identity Center application assignment for Amazon Redshift and delete the associated IAM role and policy.
Conclusion
In this post, we showed you how to enable AWS IAM Identity Center authentication for Amazon Redshift on clusters with enhanced VPC routing enabled. Your users get single sign-on with their corporate credentials, and the authentication traffic stays private to your VPC. The key concept is that Amazon Redshift, not your client, validates the access token. Because enhanced VPC routing is enabled, Amazon Redshift routes that validation call through your VPC. On a cluster running patch 204 or later, interface endpoints for sso-oauth and identitystore give Amazon Redshift a private path over AWS PrivateLink. Adding endpoints for AWS Glue, AWS Lake Formation, and Amazon S3 extends the same benefit to data lake and lakehouse queries.
Try this setup in your own environment and let us know what you think in the comments. For more information, see the following resources:
AWS IAM Identity Center integrates with external identity provider (IdP) to provide customers with a centralized authentication and authorization solution for AWS resources across AWS Organizations. AWS continues to invest into IAM Identity Center with a growing number of AWS services that natively integrate with IAM Identity Center. As your AWS organization scales, maintaining visibility into who has access to which applications and enforcing governance policies across accounts and Regions becomes increasingly complex. Identity Center helps address this by centralizing authentication and authorization for AWS resources across your organization, integrating with your external identity provider and a growing number of AWS services. However, as adoption scales, tracking access assignments and enforcing governance policies consistently becomes its own challenge.
This blog post focuses on planning your integration between an identity provider and IAM Identity Center for managed applications in your organization. We also walk through deploying and using an automated Identity Center discovery and reporting sample solution to help answer the governance and security questions:
Which users or groups have access to which AWS applications?
Who last accessed a specific AWS application and when?
Which users and groups are assigned to which IAM Identity Center applications across organization and AWS Regions?
How can you quickly generate reports to assist with compliance audits or security reviews?
The sample solution will identify associated AWS applications and the corresponding user and group assignments for the IAM Identity Center instances within your organization. The output is stored in a queryable format and generates CSV files for downstream analysis or reporting.
Plan identity governance for Identity Center application assignments
There are four key areas to start on when planning how to manage delegation and provisioning access across IAM Identity Center managed AWS applications. Bring together key stakeholders across security, governance, application, and business teams to make sure the implementation and integration will fit into the overall identity governance strategy.
Who can provision managed AWS applications: You can implement the IAM restrictions for creation of new AWS resources within AWS accounts in your organization. For example, if you restrict provisioning into a production AWS account to only infrastructure as code (IaC) IAM roles, you would continue implementing restrictions using AWS identity policies, service control policies (SCP), resource control policies (RCP), or IaC policy evaluation tools like Open Policy Agent (OPA) or Checkov.
Who manages user and group assignments: The managed application administrator handles authorization to managed applications within an AWS account. It’s recommended to clearly define roles and responsibilities across the workflow. You would have an IaC pipeline manage the integrated AWS resource provisioning with IAM Identity Center, then another workflow to allow requests to manage user and group membership for the managed application.
How authentication flows from the IdP to AWS resources: Users will authenticate into Identity Center, then be authorized to access AWS managed applications. From there, they will be authorized to access the associated AWS service and resources tied to the managed application. Depending on the AWS service, the associated downstream resources might have their own IAM principals that the users can access.
Mapping IdP identities to AWS resource access: There needs to be a link for workforce users and groups in your IdP, to Identity Center managed applications, and to downstream resources and permissions. Identifying the relationship will help you understand access within your AWS environment. Trusted identity propagation (TIP) is an additional feature of Identity Center that provides an end to end trail of the identity to the downstream service.
Create and manage an Identity Center application assignment lifeycle
After you have IAM Identity Center set up within an organization instance, your member AWS accounts can start creating associated AWS resources. Within each member AWS account, the IAM principals that provision AWS resources will need two types of service-specific IAM permissions:
The first type of IAM permissions will be specific to the AWS service you want to provision. For example, to create an Amazon SageMaker AI domain, you would need the same IAM permissions to create the SageMaker AI domain and the downstream AWS resources SageMaker AI might use.
The second type of IAM permissions is specific to IAM Identity Center. The IAM principal used to create the resource, in this example SageMaker AI, will also need permissions to manage applications within the Identity Center instance.
IAM Identity Center application Amazon Resource Names (ARNs) follow a different standard naming convention that isn’t based on the original resource name that was provided during resource creation. For example, when a user creates an Amazon Simple Storage Service (Amazon S3) bucket and sets a specific bucket name, that bucket name is included in the ARN: arn:[partition]:s3:::[bucket-name]. Identity Center application ARNs use unique identifiers (GUIDs) generated at creation time.
Manage access for an Identity Center application
After the IAM Identity Center application is created, you will need to manage access to the Identity Center application and associated AWS resources. To continue with the SageMaker AI domain example, after the domain is created, an authorized IAM principal will need to assign Identity Center users or groups from the Identity Center instance to the domain. For Identity Center, you will need two types of Identity Center IAM permissions.
The first type of IAM permissions is used to list IAM Identity Center users and groups within the Identity Center instance. This is needed to read and select specific IAM users or groups to assign to an Identity Center application.
Although IAM Identity Center users and groups have a GUID, the GUIDs aren’t clearly linked to the resource friendly names. For example, a group name could be Read-Only and the resource GUID could be 1234567890-abcdef12-3456-7890-abcd-ef1234567890 in the identity store. Additionally, the IAM actions to list users or groups require the AllUsers or AllGroups parameter. Because List actions require access to users and groups, a restrictive IAM policy can’t be used to prevent IAM principals from seeing a subset of users or groups within the identity store. The second type of IAM permission is used to create and manage application assignments for the Identity Center application within the Identity Center instance.
Because the IAM Identity Center application ARN is created using a unique application ID during creation, it’s not recommended to implement an IAM policy restricting authorized IAM principals to manage specific Identity Center applications. For example, to limit the application assignments to only a specific set of applications, you would need to:
Create the AWS resource with IAM Identity Center as the authentication mechanism
Query the Identity Center application ARN for the associated AWS resource
Identify the IAM principal that will be used for application assignments
Create or update an IAM policy associated to that IAM principal to allow application assignments for that specific application
Create or update an SCP to restrict application assignment to that specific IAM principal
In lieu of implementing resource restrictions within identity policies, you should limit management of IAM Identity Center application and application assignments to a limited number of authorized IAM principals. In addition, it is recommended to implement detective and reactive capabilities to manage Identity Center application assignments.
Plan your naming conventions and automation strategy
IAM Identity Center provides several APIs to capture information about your AWS organization instances, applications, and assignments. Before implementing automation or guardrails, you should develop a methodical approach and understand what outcome you’re working backwards from. Start by defining naming conventions and deciding what parts of the workflow you want to centralize.
Determine a naming convention for groups within your IdP: For example: AWS_<ACCT#>_<AWS_Service>_<LOB>_<ENV>_<AppName>. The IdP group name would look like: AWS_123412341234_SageMaker_Data_PROD_GTLabel.
Define the naming convention for AWS resources for your Identity Center integrated applications: For example: <AWS_Service>_<LOB>_<AppName>. The AWS resource name would look like: SageMaker_Data_GTLabel.
Define the naming convention for Identity Center application names: For example: <AWS_Service>_<LOB>_<ENV>_<AppName>. The Identity Center application name would look like: SageMaker_Data_PROD_GTLabel.
Decide on the restrictions that you want to implement within your AWS environment. Depending on your enterprise’s security standard, you can implement specific restrictions based on mapping of a similar combination of ENV (environment), AWS service, LOB (line of business), or application name.
Choose the portions of the application workflow that you want to centralize. This could include creating the application, making application assignments, or remediating issues.
As more configurations and permissions are centralized, additional overhead and bottlenecks can be introduced. It’s important to find the right balance for your enterprise. For example, if you centralize application assignments, each application team will need to submit a request to modify assignments that will be reviewed by a centralized team and could result in a delayed response. Conversely, if each application team handles their own assignments, there’s a risk that application assignments won’t align to enterprise security standards.
By understanding your goals and how you want to reach them, you can tailor the sample solution accordingly. Getting alignment on this requires planning and coordination across multiple teams within your organization. When thinking about more customized authorization logic—such as using provisioned AWS resource metadata—you should review how the specific AWS service integrates with IAM Identity Center managed applications. For example, if you want to find the Identity Center application ARN for a specific AWS resource, such as a SageMaker AI domain, use the following approach. A reverse lookup is necessary because AWS services create Identity Center applications with GUID-based ARNs that aren’t easily discoverable.
Amazon API Gateway – Provides an IAM-authenticated REST API for a Lambda function to generate and export reports as CSV files
Amazon S3 – Stores the encrypted CSV file exports, with lifecycle policies and time-limited Amazon S3 presigned download URLs
Deploy the IAM Identity Center reporting sample
The following procedure deploys the automated discovery and reporting infrastructure using AWS Cloud Development Kit (AWS CDK). Make sure you have the following prerequisites in place, then continue with the steps to set up the solution.
Prerequisites
You need to have the following to test the solution in this post.
An AWS organization with an IAM Identity Center organization instance with delegated administrator access configured
IAM Identity Center configured with at least one instance
export IDC_EXTERNAL_ID="$(uuidgen)" # alternatively you can set this value — member-account roles need the same value

cdk deploy --parameters AllowedIpRange=10.0.0.0/8 --parameters CrossAccountExternalId="$IDC_EXTERNAL_ID"
Note: AllowedIPRange is optional but recommended as a security best practice. The parameter will add a network restriction to download the Amazon S3 presigned URL export.
Optional: For AWS account-level Identity Center instance discovery, a cross-account IAM role is required.
Figure 2: Successful AWS CDK deployment of the reporting stack
After the stack is successfully deployed, obtain the CDK output values for the API Gateway URL and S3 bucket name. If using a command line to deploy, these values will be displayed after the stack successfully deploys. It can also be found in the AWS Management Console as AWS CloudFormation stack output. The output will be used for generating reports in the following sections.
Note that this stack is for the reporting stack only. Reactive monitoring and deployment are described in the next section.
After the reporting stack is successfully deployed, the automation will run on a daily schedule. The first discovery run executes immediately after deployment. You can monitor discovery execution history and detailed logs through the the AWS Step Functions console. Review the detailed Lambda function logs in Amazon CloudWatch Logs. Query discovered instances, applications, and assignments through the DynamoDB console for one-time analysis.
Generate reports for Identity Center application assignments
To generate on-demand reports as CSV files from the REST API:
You can use the generated CSV files to help identify anomalies or non-compliant assignments, such as:
Each PROD application should only have GROUP assignments. OpenSearch_PROD has a USER principal type and so is non-compliant.
Each PROD application should only allow PROD groups assigned. SageMaker_PROD has a DEV group name (Engineering-Team-Dev) assigned and so is non-compliant.
Based on the testing and analysis of the output from the IAM Identity Center governance reporting sample solution, it’s important to start thinking about what restrictions to put in place for application assignments. It’s also important to conduct this exercise before taking action within the Identity Center remediation sample solution in the next section.
IAM Identity Center remediation
The following diagram shows the IAM Identity Center remediation architecture.
The IAM Identity Center remediation sample solution deploys the following resources:
Amazon EventBridge – Matches IAM Identity Center assignment and profile events from CloudTrail (sso.amazonaws.com) and invokes the monitor function across the following IAM actions:
CreateApplicationAssignment
DeleteApplicationAssignment
PutApplicationAssignmentConfiguration
AssociateProfile
DisassociateProfile
CreateProfile
UpdateProfile
DeleteProfile
Lambda – Resolves the application and group names, validates the assignment against your naming convention, and notifies or remediates based on the configured mode
AWS KMS – Customer-managed key to encrypt the Lambda environment variables, CloudWatch logs, SNS topic, and dead-letter queue
Amazon CloudWatch – Log group stores the function’s structured, encrypted logs as an audit trail
Flexible naming policies support regex-based pattern matching for specific organizational requirements. The automation actions are logged to CloudWatch with structured JSON for additional analysis and reporting.
The following procedure deploys the remediation infrastructure using AWS Cloud Development Kit (AWS CDK). Make sure you have the following prerequisites in place, then continue with the steps to set up the solution.
Prerequisites
You need the following to run the remediation solution:
An AWS organization with an IAM Identity Center organization instance with delegated administrator access configured
IAM Identity Center configured with at least one instance and an IdP
Python 3.12 & Node.js 18 or later installed for CDK deployment
Provide your IAM instance ARN and the account ID where IAM Identity Center is administered:
git clone https://github.com/aws-samples/sample-iam-idc-application-discovery-reporting # only needed if you did not clone in the previous reporting section
cd identity-center-remediation
cdk deploy --context enableAutoDeletion=false --parameters IdentityCenterInstanceArn=arn:aws:sso:::instance/ssoins-<INSERT-ORG-INSTANCE-ID> --parameters ManagementAccountId=<INSERT-MANAGEMENT-ACCOUNT>
Note: If you don’t pass a parameter for GroupNameRegex, the default action of the sample solution is to verify the group name appears as a whole word in the application name: Case-insensitive, splitting on -, _, and spaces, so ReadOnly matches sagemaker_readonly but read does not. If different validation is needed, the sample can be deployed with the regex value for GroupNameRegex.
After the solution is deployed, we will walk through testing both a compliant and non-compliant application assignment.
Gather Identity Center and application information
For this blog, we have already created two groups within the IdP that is integrated into an IAM Identity Center instance. We also already created two applications within Identity Center instance to use. Next, we’ll need to gather information specific to the environment to run through each example.
Obtain the IAM Identity Center instance ARN and set the value.
After you have the output for IAM Identity Center groups and applications, select two groups and one application that you want to test with. You will need to set additional variables for each group GUID and application ARN. In this example, I select the following two groups (ReadOnly and Developer) for testing and set the environment variables using export:
As part of this validation, the sample solution verifies the group name appears as a whole word in the application name: Case-insensitive, splitting on the -, _, characters and spaces, so ReadOnly matches sagemaker_readonly but read does not. For different use-cases, The GroupNameRegex parameter can be used during deployment.
Test compliant and non-compliant assignments
Run the following command to add the ReadOnly group assignment to the sagemaker_readonly application:
aws sso-admin create-application-assignment --application-arn $APP_READONLY --principal-id $GRP_READONLY --principal-type GROUP
The group assignment request meets the validation criteria because the application name sagemaker_readonly contains the group name ReadOnly. The output logs for this validation exist within the associated lambda function CloudWatch log group /aws/lambda/identity-center-app-monitor”.
In this example, the logs will show:
✓ COMPLIANT - Group name found in application name
Run the following command to try to add the Developer group assignment to the sagemaker_readonly application:
aws sso-admin create-application-assignment --application-arn $APP_READONLY --principal-id $GRP_DEVELOPER --principal-type GROUP
The group assignment request doesn’t meet the validation criteria because the application name sagemaker_readonly doesn’t contain the group name Developer. The output logs for this validation exists within the associated lambda function CloudWatch log group /aws/lambda/identity-center-app-monitor. Note that the remediation action listed shows NOTIFICATION_ONLY, meaning it only sent a notification to the configured SNS topic and did not take action. If you want the group assignment to be deleted, the value should be set to enableAutoDeletion=true.
In this example, the logs will show:
✗ NON-COMPLIANT - Group name not found in application name
Scheduled reporting gives baseline visibility into IAM Identity Center managed applications. Event-driven monitoring can provide near real-time notification or enforcement. Together, these sample solutions can help align and scale Identity Center with your governance and security standards through both historical analysis and immediate response.
Clean up
For each deployed CDK stack, run the following commands in the AWS account where it was deployed.
To delete the remediation stack, run the following commands:
cd sample-iam-idc-application-discovery-reporting/identity-center-remediation
cdk destroy
To delete the reporting stack, run the following commands:
cd sample-iam-idc-application-discovery-reporting/identity-center-reporting
cdk destroy
IAM governance automation at scale
Achieving effective IAM Identity Center governance at scale requires moving beyond manual processes to automated, continuous monitoring and reporting. The following high-level steps can provide an Identity center governance framework:
Deploy the sample automation with an IAM principal that has access in your delegated administrator account.
Establish a baseline by running your first discovery and reviewing the generated reports.
Configure naming policies to match your organization’s security conventions.
Deploy the event-driven monitoring capabilities to enable real-time policy enforcement and automated response based on the security policies.
Start in notification mode to establish a baseline before enabling auto-remediation.
Integrate with your governance tools by connecting the API endpoints to your compliance dashboards or ITSM tools.
Move to auto-remediation once you have validated policies are working as expected.
Conclusion
Managing AWS IAM Identity Center at scale doesn’t have to be a manual, time-consuming process. By implementing automated discovery and reporting combined with real-time event-driven monitoring, you can maintain continuous visibility into your organization’s identity and access landscape, respond immediately to policy violations, and enforce governance policies consistently across your organization. Automation reduces operational work, strengthens security, speeds up incident response, and maintains compliance. Start by deploying these solutions to gain visibility and enable real-time enforcement.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.
Last week I had the joy of participating in Amazon’s “Bring Your Kids to Work Day” with my 7 year old son. We commuted together into the New York City office, his first real rush hour train ride, and spent the day exploring how Amazon uses AI, machine learning, and robotics to deliver packages to customers all over the world. Watching his eyes light up as he saw robots navigating a fulfillment center reminded me why so many of us got into technology in the first place. There’s nothing quite like seeing that sense of wonder when something complex clicks.
That same energy carried into the week’s launches. We’ve got updates across AI pricing, observability, multicloud networking, and data management. Let’s dive in.
Headlines Amazon Bedrock announces up to 80% lower prices for OpenAI GPT‑5.6 models – If you’re using OpenAI’s GPT‑5.6 family through Amazon Bedrock, your costs just dropped significantly. Effective July 30, on-demand inference prices for GPT‑5.6 Luna are reduced by 80%, while GPT‑5.6 Terra prices are reduced by 20%. Luna now costs $0.20 per million input tokens and $1.20 per million output tokens, making it one of the most affordable frontier-class models available. These price reductions apply automatically — no action required on your part. Read more
Last week’s launches Here are some launches and updates from this past week that caught my attention:
Amazon CloudWatch announces managed Prometheus collectors – Amazon CloudWatch now supports collecting Prometheus metrics from your AWS infrastructure using fully managed collectors, enabling you to monitor Amazon EKS, Amazon EC2, Amazon ECS, Amazon MSK, and Amazon OpenSearch Service workloads without deploying or managing any agents. If you’ve been maintaining your own Prometheus scraping infrastructure, this removes a significant operational burden. Read more
AWS Interconnect — multicloud connectivity with Oracle Cloud Infrastructure is now generally available – AWS Interconnect is the first purpose-built multicloud connectivity product of its kind, allowing you to quickly provision resilient, scalable private connections between AWS and other cloud providers. With this GA launch for Oracle Cloud Infrastructure (OCI), you can establish private cross-cloud networking without traversing the public internet, making it easier to run multicloud architectures with the security and performance your workloads demand. Read more
AWS IAM Identity Center extends multi-Region support to Identity Center directory – You can now replicate IAM Identity Center from your primary AWS Region to additional Regions when using the Identity Center directory as your identity source. If IAM Identity Center is affected by a disruption in the primary Region, your users continue to have access to their AWS accounts using provisioned entitlements in additional Regions. This feature was previously available only for instances connected to external identity providers. Read more
Amazon S3 Tables now supports the Variant data type for Apache Iceberg V3 – Amazon S3 Tables adds support for the Variant data type, introduced in the Apache Iceberg V3 table format specification. Variant provides a high-performance, native solution for managing semi-structured data within your data lake — think IoT sensor data, application logs, and other schema-flexible payloads — without resorting to JSON blobs. Read more
Other AWS news Here are some additional posts and resources that you might find interesting:
Installing and updating the AWS CLI with single-line commands – A new blog post from the Developer Tools team that simplifies AWS CLI installation and updates across platforms with single-line commands. If you manage CLI versions across teams or in CI pipelines, this is a nice quality-of-life improvement.
Deploying Kimi K3 on Amazon SageMaker HyperPod and Amazon EKS – A step-by-step guide for deploying Moonshot AI’s Kimi K3 model on AWS infrastructure using SageMaker HyperPod and Amazon EKS. If you’re evaluating large-scale model deployment options, this walks through the full workflow.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits – AWS Summits are free events that bring the cloud and AI community together to connect, learn, and explore the latest technologies. Browse the full calendar to find a Summit near you in the second half of 2026.
AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
Organizations with lines of business operating across multiple AWS Regions increasingly run analytics workloads on globally distributed data. These organizations want to manage users and groups centrally, typically in the AWS Organizations management account and in a single Region, while still letting each line of business access data from the Region where its workloads run. Organizations should govern access based on the actual workforce user and their group memberships in the corporate directory.
With multi-Region support for AWS IAM Identity Center, organizations can federate workforce identities into a single organization instance in their primary Region. After you replicate this instance to additional Regions, member accounts running services such as Amazon Redshift or Amazon Athena in those Regions can integrate with IAM Identity Center locally, to resolve the same centrally managed users and groups.
This solution uses Trusted Identity Propagation (TIP), a capability that passes a user’s Identity Center identity and group memberships through a chain of AWS services. With TIP, when a user authenticates through Identity Center, that identity context flows to downstream services like AWS Lake Formation and Amazon S3 Access Grants. With this approach, you get consistent, identity-based access control without additional AWS Identity and Access Management (IAM) role configurations.
In Part 1 of this series, we showed how to simplify enterprise data access using the Amazon Redshift integration with Amazon S3 Access Grants. We demonstrated how to grant Amazon Simple Storage Service (Amazon S3) permissions to AWS IAM Identity Center users and groups using S3 Access Grants, and tested the integration using a federated user to unload and load data between Amazon Redshift and Amazon S3 within a single AWS Region.
In this post, we extend that solution across AWS Regions. We introduce a fictional company, AnyCompany Global, to illustrate how organizations with global operations can use AWS IAM Identity Center Multi-Region to set up consistent, identity-based access to Amazon Redshift and Amazon S3 Tables across Regions.
Specifically, we demonstrate:
How IAM Identity Center Multi-Region replicates identity data so that the same users and groups are available in each enabled Region.
How AWS Lake Formation grants fine-grained table-level and column-level access to S3 Tables based on group membership.
How S3 Access Grants controls UNLOAD/COPY operations to Amazon S3 based on the same identity.
We also show how to connect with your preferred SQL client.
Fictional scenario: AnyCompany Global
AnyCompany Global is a retail analytics company with a centralized IT team and distributed analytics teams. They use the following personas:
Alice — IT administrator (manages IAM Identity Center and AWS accounts).
Bob — platform engineer (sets up data infrastructure in us-west-2).
Ethan — data analyst (member of the awssso-sales group, queries data).
AnyCompany Global has two AWS accounts:
Account A (us-east-1) — management account with IAM Identity Center.
Account B (us-west-2) — analytics account with Amazon Redshift, Amazon S3, and the AWS Glue Data Catalog.
The same IAM Identity Center user (Ethan) authenticates once and accesses data in Account B (us-west-2) using the same credentials and group memberships — you don’t need additional user provisioning because IAM Identity Center replicates identities to the secondary Region.
Solution overview
The following diagram illustrates the multi-account, multi-Region architecture. Account A (us-east-1) hosts IAM Identity Center, which replicates identities to us-west-2 where Account B runs the analytics workloads.
Figure 1: Multi-account, multi-Region architecture with S3 Access Grants, AWS Lake Formation, and IAM Identity Center.
This solution demonstrates two complementary data access patterns, both controlled by the end user identity:
Pattern
Access method
Permission controlled by
Pattern A
SELECT on S3 table bucket through Amazon Redshift Spectrum
Lake Formation
Pattern B
UNLOAD/COPY to and from Amazon S3
S3 Access Grants
The solution workflow includes the following steps:
Ethan connects from Amazon Redshift Query Editor v2 in us-west-2 and authenticates via the IAM Identity Center endpoint (replicated to us-west-2) using his corporate IdP credentials.
For Pattern A (SELECT): Amazon Redshift queries the Amazon S3 Tables catalog (s3tablescatalog). Lake Formation evaluates Ethan’s IAM Identity Center group membership and grants access to the cataloged data.
For Pattern B (UNLOAD/COPY): Amazon Redshift requests temporary credentials from S3 Access Grants in us-west-2. S3 Access Grants evaluates the request, matches Ethan’s identity and group membership, and vends scoped temporary credentials for the authorized S3 location.
Ethan runs SELECT to query data through Lake Formation, and UNLOAD to write data to Amazon S3 through S3 Access Grants. You don’t need an IAM role ARN in the commands.
Walkthrough
The following sections walk you through enabling IAM Identity Center Multi-Region, configuring Amazon S3 Tables with Lake Formation in the secondary Region, testing both access patterns, and verifying the result with AWS CloudTrail. Start with the prerequisites, then complete each step in order.
Prerequisites
You should have the following prerequisites already set up:
AWS Organizations enabled with at least two AWS accounts – Centralized Account(Region 1) and Member Account(Region2)
IAM Identity Center enabled in the management account (Account A, us-east-1) with a delegated administration account
Corporate IdP integrated with IAM Identity Center (users and groups synced, for example, awssso-sales and awssso-finance groups).
Resource sharing enabled in your organization with AWS Resource Access Manager (AWS RAM)
Complete solution from Part 1 replicated in us-west-2 (Account B), including:
Amazon Redshift cluster (in us-west-2) with IAM Identity Center integration enabled (using the replicated Identity Center endpoint in us-west-2).
S3 Access Grants instance configured with IAM Identity Center association
Amazon S3 bucket (for example, amzn-s3-demo-bucket-west) with folders for each group (for example, awssso-sales/, awssso-finance/).
IAM role for S3 Access Grants (for example, iamidcs3accessgrant) with trust policy and permissions policy.
S3 Access Grants location registered and grant created for the awssso-sales group.
S3 Access Grants enabled on the Amazon Redshift managed application under Trusted identity propagation
Cross-account resource sharing via AWS RAM (if Amazon Redshift and S3 Access Grants are in different accounts)
Lake Formation enabled on the Amazon Redshift managed application under Trusted identity propagation
Lake Formation and Glue permissions added to the IAM role used in the Amazon Redshift managed application (for example, IAMIDCRedshiftRole). For the required permissions, see Querying data through AWS Lake Formation.
Note: Creating and using AWS resources in this tutorial incurs charges, including AWS Key Management Service (AWS KMS) keys, S3 table buckets, Amazon Redshift clusters, and Amazon S3 storage. See the cleanup section at the end of this post to avoid ongoing charges.
Step 1: Set up IAM Identity Center Multi-Region
Alice performs this step in the management account (Account A, us-east-1). IAM Identity Center uses encryption at rest for identity data. To enable multi-Region, you must first create a multi-Region customer-managed AWS Key Management Service (AWS KMS) key and replicate it to the additional Region.
Create a multi-Region AWS KMS key
On the AWS KMS console in us-east-1, choose Create key.
For Key type, select Symmetric.
For Key usage, select Encrypt and decrypt.
Under Advanced options, select Multi-Region key.
Provide an alias (for example, idc-multi-region-key).
Figure 2: Replica key configured for the additional Region.
Add us-west-2 to IAM Identity Center
On the IAM Identity Center console in us-east-1, in the navigation pane, choose Settings.
Choose Add Region.
From the Region list, select US West (Oregon) us-west-2. The list shows Regions where you replicated the customer-managed AWS KMS key.
Choose Add Region.
A blue banner indicates that Identity Center is replicating your workforce identities, configuration, and metadata to the new Region. After the initial replication, the Replication Status column changes to Replicated. Your Identity Center endpoints in us-west-2 are now active.
Figure 3: IAM Identity Center settings showing the multi-Region replica key added for us-west-2.
Update your IdP configuration for the additional Region
You’ve successfully replicated your Identity Center instance to the Oregon (us-west-2) Region. Your workforce identities are now available in that additional Region and can use the new AWS access portal endpoint.
To make sure AWS managed application (service provider-initiated) authentication redirect user to respective application, add the ACS URL for the additional Region so that the app contains both Regional ACS URLs.
In the following section highlighted in red, you can view all ACS URL information:
Figure 4: IAM Identity Center settings showing the View ACS URLs option.
Copy the respective ACS URL as shown in the following figure:
Figure 5: IAM Identity Center settings showing the ACS URLs for both Regions.
Use the following instructions to add the ACS URL for the additional Region in your Identity Center application in Okta:
Log in to the Okta portal as an Admin.
Expand the Applications drop-down in the left pane, then choose Applications
Choose your Identity Center Application
Select the Sign-on tab and choose Edit in the Settings windows.
In the AWS SSO ACS URL1 box under Advanced Sign-on Settings – add the additional ACS URL
Choose Save.
Figure 6: Okta application for IAM Identity Center Sign-on tab to add ACS URLs.
Create a permission set for the secondary Region
Create a permission set in the management account to grant federated users console access to Amazon Redshift Query Editor V2 in the secondary Region (us-west-2). For more information about permission sets, see Permission sets.
Choose Next. Enter a permission set name (for example, Redshift-QEV2-West).
Under Relay state, set the default to the Query Editor V2 URL for the secondary Region: https://us-west-2.console.aws.amazon.com/sqlworkbench/home.
Choose Next, then Create.
After creation, assign this permission set to the relevant IAM Identity Center group (for example, awssso-sales) for Account B (us-west-2).
Step 2: Set up Amazon S3 Tables integration with AWS Glue Data Catalog and Lake Formation in Account B (us-west-2)
In this step, the data lake administrator (Bob) sets up Amazon S3 Tables with Lake Formation for fine-grained access control. He completes the following tasks:
Create an S3 tables bucket.
Enable S3 Tables integration with AWS Glue Data Catalog and Lake Formation.
Register the table bucket with Lake Formation (removes default IAM-based access).
Grant Lake Formation permissions to an IAM Identity Center group (awssso-sales) so that only authorized users can query data through Trusted Identity Propagation.
Step 2.1: Remove default Lake Formation permissions
Before creating S3 Tables resources, disable the default IAMAllowedPrincipals grants that Lake Formation applies to new databases and tables. By default, Lake Formation grants IAMAllowedPrincipals access to new resources, which means that standard IAM policies (rather than Lake Formation permissions) control access. For identity-based access through Trusted Identity Propagation, you need Lake Formation to be the sole arbiter of access.
The order matters. If you remove these defaults before registering the S3 Tables resource, Lake Formation will not apply IAMAllowedPrincipals to your S3 Tables catalog or its children. If you register the resource first, you need to manually revoke the IAMAllowedPrincipals grants from each resource.
From the console
Open the Lake Formation console in your target Region (for example, us-west-2).
In the left navigation, choose Administration → Data Catalog settings.
Uncheck both options:
Use only IAM access control for new databases
Use only IAM access control for new tables in new databases
Choose Save.
Figure 7: Lake Formation Data Catalog settings with default IAM access control disabled.
Optional: Verify Lake Formation default permissions through the AWS CLI
Confirm both CreateDatabaseDefaultPermissions and CreateTableDefaultPermissions are empty arrays ([]).
Add AWSServiceRoleForRedshift as a read-only admin
If you plan to query S3 Tables from Amazon Redshift Query Editor V2, you must add the Amazon Redshift service-linked role as a Read-Only Admin in Lake Formation. Complete the following steps:
In the Lake Formation console, go to Administration → Administrative roles and tasks.
Under Data lake administrators, choose Add. Choose Read only administrator.
From the menu, choose AWSServiceRoleForRedshift.
Choose Confirm.
Important: Without this, Amazon Redshift Query Editor V2 doesn’t display external databases from s3tablescatalog. The Amazon Redshift service-linked role needs read-only admin access to browse the Data Catalog on behalf of users.
Step 2.2: Create the Lake Formation data access role for S3 Tables
Create an IAM role that Lake Formation assumes to generate temporary, scoped credentials on behalf of users requesting access to S3 Tables data. Lake Formation uses this role (instead of its service-linked role) because Trusted Identity Propagation requires sts:SetContext in the trust policy, which is not available on the service-linked role. Without a custom role with this permission, Lake Formation cannot propagate the user’s IAM Identity Center identity when accessing S3 Tables.
Register the S3 Tables resource with Lake Formation using the data access role. This step lets Lake Formation manage access to S3 Tables through the Data Catalog and creates the s3tablescatalog federated catalog automatically.
Open the Lake Formation console and complete the following steps:
Choose Catalogs in the navigation pane and choose Enable S3 Table integration.
Figure 8: Lake Formation Catalogs page with the Enable S3 Table integration option.
Select the IAM role and select Allow external engines to access data in Amazon S3 locations with full table access. Choose Enable.
Figure 9: Enable S3 Table integration dialog with the IAM role and external-engine access configured.
Important: Verify that the --role-arn matches the exact ARN of the role created in Step 2.2 (including the path). A mismatch (e.g., role/service-role/LFAccessRole-S3Tables vs role/LFAccessRole-S3Tables) will cause credential vending failures later.
Confirm the S3 Tables entry shows WithFederation: true and the correct role ARN.
Step 2.4: Create the S3 table bucket and namespace
Create an S3 table bucket and a namespace. Complete the following steps on the Amazon S3 console:
In the navigation pane, choose Table buckets.
Choose Create table bucket.
On the next page, enter the bucket name as <TABLE_BUCKET_NAME>.
Keep the other options as default and choose Create table bucket.
After you create it, the AWS Management Console redirects you to the list of table buckets. Choose the table bucket <TABLE_BUCKET_NAME>.
Choose Create table with Athena.
Create a namespace in S3 Tables (equivalent to a database in AWS Glue Data Catalog). Enter the namespace (database) name as <NAMESPACE_NAME> and choose Create namespace.
After you remove default permissions, you need to give your Admin role explicit Lake Formation permissions to create tables. Because your Admin role is a Data Lake Admin, you can already see s3tablescatalog in the Amazon Athena console, but creating tables requires an explicit grant.
From the console
Open the Lake Formation console in your Region.
Choose Data permissions → Grant.
Under Principals, select IAM users and roles and choose your Admin role.
Under LF-Tags or catalog resources, select Named Data Catalog resources.
For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
For Databases, select your database (for example, customer_ns_db).
Select Super for Database permissions and Grantable permissions.
Choose Grant.
After this grant, you can create and insert data into tables from the Athena console.
Note: Your Admin role must be a Data Lake Admin (configured in Step 2.1) to browse s3tablescatalog in Athena. You need the explicit database grant for write operations (CREATE TABLE, INSERT).
Step 2.6: Create a table from the Athena console
Open the Amazon Athena console in your Region.
In the Data source menu, select AwsDataCatalog.
For Catalog, choose s3tablescatalog/<Table_Bucket_Name>.
Step 2.7: Grant permissions to the IAM Identity Center group
Give your IAM Identity Center group access to query tables. This step enables Trusted Identity Propagation (TIP) for this group. When users in the group access data through TIP-integrated services like Amazon Redshift, Lake Formation evaluates their IAM Identity Center group membership and enforces table-level and column-level permissions accordingly.
From the console
Grant DESCRIBE on the database:
Open the Lake Formation console in your Region.
Choose Data permissions → Grant.
Under Principals, select IAM Identity Center and choose your IAM Identity Center group (for example, awssso-sales).
Under LF-Tags or catalog resources, select Named Data Catalog resources.
For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
For Databases, select your database (for example, customer_ns_db).
For Database permissions, select Describe.
Choose Grant.
Grant SELECT and DESCRIBE on tables:
Choose Data permissions → Grant.
Under Principals, select IAM Identity Center and choose your IAM Identity Center group (for example, awssso-sales).
Under LF-Tags or catalog resources, select Named Data Catalog resources.
For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
For Databases, select your database (for example, customer_ns_db).
For Tables, select All tables (or a specific table).
For Table permissions, select Select and Describe.
Choose Grant.
Tip: You can also configure column-level or row-level permissions for fine-grained access control. When granting on a specific table, additional options for Column permissions and Data filters become available.
Step 2.8: Optional: Verify the Lake Formation permissions
Your Admin role with ALL permissions at the database level.
Your IAM Identity Center group with DESCRIBE permissions at the database level.
Your IAM Identity Center group with DESCRIBE on ALL_TABLES and SELECT on ALL_TABLES (with ColumnWildcard) at the table level.
No IAM_ALLOWED_PRINCIPALS entries.
Step 2.9: Create Amazon Redshift tables and grant permissions
Connect to the Amazon Redshift cluster in us-west-2 as an admin user and create Redshift local tables. Grant permissions on those local resources to IAM Identity Center groups.
Create a schema and table
CREATE SCHEMA IF NOT EXISTS sales_schema;

CREATE TABLE IF NOT EXISTS
sales_schema.store_sales (
  customer_id INTEGER ENCODE az64,
  product VARCHAR(50),
  sales_amount INTEGER ENCODE az64
)
DISTSTYLE AUTO;

-- Insert sample data
INSERT INTO sales_schema.store_sales VALUES
  (1, 'Laptop', 1200),
  (2, 'Phone', 800),
  (3, 'Tablet', 450),
  (4, 'Monitor', 350),
  (5, 'Keyboard', 120);
Grant permissions to the IAM Identity Center group
GRANT USAGE ON SCHEMA sales_schema TO ROLE "awsidc:awssso-sales";
GRANT SELECT, INSERT FOR TABLES IN SCHEMA sales_schema TO ROLE "awsidc:awssso-sales";

-- Grant access to the S3 Tables external database in Redshift (for Lake Formation queries on customer profiles)
GRANT USAGE ON DATABASE "customers3tables@s3tablescatalog" TO ROLE "awsidc:awssso-sales";
Step 3: Test the solution
In the management account, navigate to the IAM Identity Center console and copy the AWS access portal URL (for example, https://d-1234560789.awsapps.com/start) from the dashboard.
Log out from the management account and paste the AWS access portal URL in a new browser window.
A pop-up redirects you to your IdP login page. Enter Ethan’s IdP credentials.
After successful authentication, you’re logged into the AWS console as a federated user. Select the QEV2 permission set for the secondary Region (us-west-2).
In Query Editor V2, open the context (right-click) menu on your Amazon Redshift instance, choose Create connection, and for Authentication, select IAM Identity Center.
Because your IdP credentials are already cached, the browser reuses them automatically. You’re now connected to Amazon Redshift.
Pattern A: Query the S3 table catalog using Lake Formation permissions
Query the customer profile data through s3tablescatalog. Lake Formation enforces access based on Ethan’s IAM Identity Center group membership:
SELECT *
FROM "customers3tables@s3tablescatalog"."customer_ns_db"."customer_profiles";
Figure 10: Query results from s3tablescatalog returned through Lake Formation in Amazon Redshift Query Editor V2.
This query reads customer profile data from Amazon S3 through Amazon Redshift Spectrum, with Lake Formation controlling who can access which tables and columns.
Pattern B: Unload data to Amazon S3 using S3 Access Grants
Run the UNLOAD command to write data from Amazon Redshift to the S3 bucket:
UNLOAD ('SELECT * FROM "dev"."sales_schema"."store_sales"')
TO 's3://west-idc-amzn-s3-demo-bucket/awssso-sales/';
You don’t need an IAM role ARN in the command. S3 Access Grants handles authorization based on Ethan’s IAM Identity Center identity and group membership, propagated across Regions using IAM Identity Center Multi-Region support.
Verify the data in Amazon S3
On the Amazon S3 console, navigate to s3://west-idc-amzn-s3-demo-bucket/awssso-sales/ and verify that the unloaded data files are present.
Join Lake Formation data with locally loaded Amazon Redshift data
Combine customer profile data (queried via Lake Formation) with sales data (loaded via S3 Access Grants) using the shared customer_id column:
SELECT c.first_name, c.last_name, c.membership_tier,
  s.product, s.sales_amount
FROM "customers3tables@s3tablescatalog"."customer_ns_db"."customer_profiles" c
JOIN  dev.sales_schema.store_sales s ON c.customer_id = s.customer_id
ORDER BY s.sales_amount DESC;
Figure 11: Joined results from S3 Tables and Amazon Redshift local data, ordered by sales amount.
This shows that you can join S3 Tables data with Amazon Redshift using the same IAM Identity Center identity.
Verify access control
To confirm that S3 Access Grants is enforcing access, try accessing a folder Ethan does not have a grant for:
UNLOAD ('SELECT * FROM "dev"."sales_schema"."store_sales"')
TO 's3://west-idc-amzn-s3-demo-bucket/awssso-finance/';
This should return an access denied error, confirming that S3 Access Grants is controlling access based on the user’s identity and group membership.
Step 4: Verify with AWS CloudTrail
You can verify that Amazon Redshift used both S3 Access Grants and Lake Formation for authorization by checking AWS CloudTrail:
On the CloudTrail console, choose Event history.
Filter by Event source: s3.amazonaws.com. Look for GetDataAccess events (S3 Access Grants).
Filter by Event source: lakeformation.amazonaws.com. Look for GetDataAccess events (Lake Formation).
Both event types show Ethan’s IAM Identity Center user identity, confirming trusted identity propagation works end-to-end for both access patterns.
Other related integration guides
The following table lists related blog posts and integration guides covering additional identity-based access patterns with Amazon Redshift. Although many of these were written for single-Region deployments, you can extend them to multi-Region environments by first enabling IAM Identity Center Multi-Region as described in Step 1 of this post. Use the table to find the guide that matches your identity provider and tooling:
Integration / use case
Identity provider
What it covers
Blog link
Amazon Redshift federated permissions
Any
Centralize permission management across multiple Amazon Redshift clusters within a Region using IAM Identity Center-linked database roles.
When implementing this multi-Region architecture, keep the following operational and configuration considerations in mind. These reflect common challenges and design decisions encountered during deployment:
IAM Identity Center Multi-Region requires a customer-managed multi-Region AWS KMS key replicated to each additional Region before you can add the Region to Identity Center.
S3 Access Grants instances are regional. You need a separate instance in each Region where your users access data. A bucket must be in the same Region as the Access Grants instance that manages it.
IAM Identity Center Multi-Region provides the same user and group identities across Regions, so you can use the same group IDs in grants across Regions.
You must register Lake Formation data locations with a customer-managed role that includes sts:SetContext in its trust policy. For S3 Tables, use aws lakeformation register-resource with the --with-federation flag and the resource ARN format arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*. Using the service-linked role causes the error: Cannot vend credentials from service-linked role to Identity Center principal.
SELECT and UNLOAD use different permission models. Lake Formation controls query-time access to cataloged data (SELECT through Spectrum). S3 Access Grants controls direct Amazon S3 access (COPY/UNLOAD). Both use the same IAM Identity Center identity.
The Amazon Redshift managed application IAM role must include sts:SetContext in its trust policy and have both Lake Formation/Glue and S3 Access Grants permissions.
Cross-account setup requires AWS RAM resource sharing for S3 Access Grants and proper IAM Identity Center application configuration in the analytics account.
Scoped vs object-level permissions in Amazon Redshift. When granting permissions with GRANT ... FOR TABLES IN SCHEMA, use REVOKE ... FOR TABLES IN SCHEMA to remove them. The REVOKE ... ON ALL TABLES IN SCHEMA syntax only removes object-level permissions, not scoped permissions.
The Lake Formation data access role for S3 Tables requires sts:SetContext in its trust policy (for TIP) and s3tables:* permissions on the table bucket resources.
AWSServiceRoleForRedshift must be a Read-Only Admin in Lake Formation for Amazon Redshift Query Editor V2 to display external databases from s3tablescatalog.
Federated catalog CatalogId format. When using CLI commands for S3 Tables resources in Lake Formation, use the full path format: <ACCOUNT_ID>:s3tablescatalog/<TABLE_BUCKET_NAME>. Using the account ID alone returns empty results.
Clean up
To avoid ongoing charges, clean up the resources created in this post:
Delete the S3 table bucket (delete tables → namespaces → bucket using aws s3tables CLI commands).
Deregister the S3 Tables resource from Lake Formation (aws lakeformation deregister-resource --resource-arn "arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*").
Delete s3tablescatalog from Glue (aws glue delete-catalog --catalog-id "s3tablescatalog").
Delete the LFAccessRole-S3Tables IAM role and associated policies.
Delete the S3 Access Grants instance and grants in us-west-2.
Delete the S3 bucket used for UNLOAD/COPY in us-west-2.
Delete the iamidcs3accessgrant IAM role and associated policies.
Deregister the S3 data location from Lake Formation.
Delete the Lake Formation IAM Identity Center integration.
Delete the Amazon Redshift cluster in us-west-2 if you created one for testing.
Remove us-west-2 from IAM Identity Center Multi-Region (if no longer needed).
Schedule deletion of the AWS KMS replica key in us-west-2 (minimum 7-day waiting period).
Conclusion
In this post, we extended the Amazon Redshift and S3 Access Grants integration to a multi-Region setup using IAM Identity Center Multi-Region replication. We demonstrated two complementary data access patterns: SELECT through Lake Formation for fine-grained access control on S3 Tables data, and UNLOAD/COPY through S3 Access Grants for direct Amazon S3 access. Both patterns use the same IAM Identity Center identity for access control. We also showed how to set up a customer-managed multi-Region AWS KMS key, enable IAM Identity Center in an additional Region, configure Amazon S3 Tables with Lake Formation for identity-based access control using Trusted Identity Propagation, and replicate the complete S3 Access Grants setup in a different Region and account.
With this approach, AnyCompany Global’s analysts authenticate once and access data in any enabled Region while Lake Formation and S3 Access Grants enforce per-user, per-group access policies.
For additional guidance, refer to the following resources:
Avanse Financial Services is one of India’s leading education loan providers. Their Data Engineering Team had built a data lake on AWS using Amazon Simple Storage Service (Amazon S3), Amazon Athena, and AWS Glue for data ingestion and processing. However, their analytics and reporting layer ran on an external analytics application that wasn’t integrated with AWS. Data had to be copied from Amazon S3 into this external application before analysts could run any report, its license consumed a significant portion of their budget despite low utilization, and every integration with AWS services required custom-built pipelines.
After evaluating their options, Avanse migrated to a cloud-native lakehouse architecture using Amazon SageMaker Unified Studio, which unified their data engineering, analytics, and artificial intelligence (AI) workflows in a single governed environment on AWS. In this post, we walk through their migration journey so you can adapt their approach to your own environment.
Why Avanse chose to modernize
The separation between their AWS data lake and their external analytics application created five problems:
Daily data synchronization bottleneck. Every report required a 4-hour batch copy from Amazon S3 into the external analytics application before analysts could query it. Business decisions were based on data that was at least a day old.
Fixed licensing costs disconnected from usage. The external analytics application charged an annual fee regardless of how many queries analysts ran. Avanse needed usage-based pricing that matched what they actually consumed, not a fixed fee for capacity they weren’t using.
Limited auditability. The external analytics application ran on a shared server where different business units (risk, collections, portfolio management) shared the same resources. It lacked granular audit trails, making it difficult to trace who accessed what data and when, or to allocate costs per team.
No centralized data discovery. Although AWS Glue Data Catalog managed schema metadata for the data lake, the external analytics application couldn’t access it. Analysts working in that application relied on folder structures and manual documentation to find the right datasets, slowing onboarding and increasing the risk of using outdated data.
Disconnected from AWS services. The external analytics application couldn’t query data in Amazon S3 or use AWS Glue catalogs natively. Every data flow required connectors and custom-built pipelines, adding maintenance overhead.
Additionally, some datasets were stored on Network File System (NFS) storage outside of Amazon S3, creating another data silo that needed to be consolidated.
Avanse chose Amazon SageMaker Unified Studio because it addressed all five challenges: direct querying of data in Amazon S3 avoiding synchronization, usage-based compute through Amazon Athena and Amazon EMR Serverless, project-based isolation with per-project billing, lineage tracking with AWS IAM Identity Center, and native integration with their existing AWS services.
Solution overview
The core architectural change was moving from a two-application model to a single integrated stack:
Previous architecture
Avanse’s data ingestion and processing ran on AWS (Amazon S3, AWS Glue, Athena), but analytics and reporting ran on an external analytics application. Data had to be batch-copied from Amazon S3 into this external application daily before analysts could query it. Each system had its own access controls, and there was no shared catalog or lineage tracking between them.
New architecture
Analytics now run directly against data in Amazon S3 through Amazon SageMaker Unified Studio. There’s no data copy step. Analysts query the same data that the ingestion pipelines produce, using Athena for SQL and EMR Serverless for large-scale processing. Governance, access control, and lineage are centralized through IAM Identity Center and SageMaker Catalog.
The following diagram illustrates the target architecture. It follows a lakehouse pattern, storing data in open formats on Amazon S3 while maintaining ACID transaction support for the consistency financial regulators expect.
The architecture has three layers:
Data layer – Amazon S3 stores data in open formats (Parquet, Delta Lake) with S3 Intelligent-Tiering for automatic cost optimization. AWS Glue Data Catalog maintains schema metadata, making data discoverable across tools.
Compute layer – Amazon SageMaker Unified Studio provides project-based workspaces organized by business function. Collections uses the built-in SQL Query Editor powered by Athena, Risk Reporting uses JupyterLab for interactive analysis, and MIS runs large-scale Spark jobs through Amazon EMR Serverless. AWS Glue ETL handles data transformations and AWS Lambda provides event-driven triggers for report generation. For machine learning (ML) workloads, Amazon SageMaker AI supports model training and deployment, with Amazon Bedrock available for generative AI capabilities such as enhancing risk narratives.
Governance layer – IAM Identity Center provides SSO and audit logging across workspaces. SageMaker Catalog serves as the business glossary with data lineage tracking and access controls. Amazon DataZone connects components through a common metadata layer.
Migration journey
Avanse followed a five-phase approach. The timelines can be adapted to your environment, but the systematic progression from validation through production deployment is key.
Phase 1: Technical validation (72-hour workshop)
Avanse started with a focused 72-hour workshop using isolated SageMaker environments where developers could experiment without impacting production. Their team tested SQL analytics against existing Athena tables and validated that Python and PySpark could replicate their existing analytics workflows.
The team confirmed that querying data directly in Amazon S3 addressed their synchronization bottleneck entirely. The 4-hour daily data copy was no longer necessary, which validated the migration approach.
Phase 2: Data migration and storage optimization
Avanse migrated datasets from NFS storage and legacy analytics formats into Amazon S3, consolidating the data into a single location. They implemented S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns, optimizing costs without impacting retrieval performance.
They replaced legacy analytics connectors with native Athena workgroups within SageMaker Unified Studio, avoiding data synchronization entirely. Source data remained in Amazon S3, queryable by both Athena SQL and SageMaker notebooks, establishing a single source of truth.
Phase 3: Compute modernization
Avanse moved from a shared analytics server to project-based isolation in SageMaker Unified Studio. Each business function (Risk Reporting, Collections, MIS) received its own project with dedicated compute spaces running JupyterLab. Project-specific IAM execution roles provided access controls and cost allocation per business unit.
A single browser-based URL with multi-factor authentication (MFA) now provides access to SQL analytics using the built-in query editor, ML development in JupyterLab notebooks, and big data processing through Amazon EMR Serverless. This replaced the need for local analytics client installations.
Phase 4: Governance implementation
Avanse deployed SageMaker Catalog as their central business data catalog. Analysts now discover approved datasets through semantic search rather than navigating folder structures or relying on manual documentation. They mapped technical Athena table names to business terms. For example, analysts search for “collection efficiency” and find the relevant tables with descriptions, schemas, and lineage.
Lineage capture traces each metric in risk reports back to source tables, transformations, and intermediate datasets. Every action (notebook execution, SQL query, data access) is tied to IAM Identity Center users, creating the comprehensive audit trail their compliance team needed.
Phase 5: Use case migration
Rather than attempting a big-bang migration, Avanse moved critical workflows one at a time:
Portfolio MIS (Monthly/Fortnightly)
Previously required the daily 4-hour data copy from Amazon S3 into the external analytics application before report generation could begin. Avanse avoided the data synchronization step entirely and now generates MIS reports by querying existing Athena tables directly in Amazon S3. Because the source data was already on AWS, there was no need to involve the external application for this activity. Report generation dropped from hours to under 30 minutes.
Collection Efficiency and Bounce Calculation
Ported complex legacy analytics procedures for calculating metrics like collection efficiency and bounce rates to event-driven processing using AWS Glue ETL, AWS Lambda, and PySpark jobs for high-volume data aggregation. The serverless execution model charges only for compute time consumed.
EDW Risk Reporting
Large-scale regulatory joins of Enterprise Data Warehouse assets previously ran as legacy scheduled procedures. These now run as SQL queries in the SageMaker Unified Studio query editor, where analysts execute them on-demand or schedule them through Athena workgroups. The distributed query engine handles complex multi-table joins spanning millions of rows.
Scorecard Generation
Model building shifted from the external analytics application to SageMaker AI workflows. Data scientists use JupyterLab with Python libraries and deploy models directly to SageMaker endpoints, avoiding data movement between separate environments.
Overcoming technical challenges
One technical challenge was code migration. Avanse’s analytics code base contained years of accumulated proprietary scripts and procedures. Direct line-by-line translation was not practical. Instead, they took a pragmatic approach: basic data transformations moved to SQL in Athena, complex business logic was rewritten in PySpark for scalability, and statistical procedures were replaced with Python libraries like pandas and scikit-learn. The approach was to focus on what the code accomplishes, then implement it using cloud-native patterns.
The other technical challenge was performance validation. The team needed to confirm that querying data in Amazon S3 would deliver acceptable performance compared to the external analytics application’s in-memory processing. Queries against Parquet-formatted data in Amazon S3 using Athena delivered comparable performance for standard reporting workloads, while avoiding the 4-hour daily data synchronization step entirely. For large-scale regulatory joins spanning millions of rows, Amazon EMR Serverless provided distributed Spark processing that completed in minutes rather than the hours required in the external application.
Reduced through S3 Intelligent-Tiering, which automatically moves data between access tiers based on usage patterns
Report generation
From over 4 hours (including data synchronization from Amazon S3 to the external analytics application) to under 30 minutes with direct Amazon S3 querying
Compliance audits
From weeks of manual investigation to days with automated lineage reports
Compute costs
Usage-based serverless model replaced always-on external analytics infrastructure
Collaboration
Unified browser-based environment for data scientists, analysts, and engineers
“By adopting SageMaker Unified Studio, we as the Data Team eliminated legacy licensing costs, reduced storage and compute expenses with a serverless, usage-based model, and accelerated our periodic report generation. At the same time, we transformed compliance and collaboration by cutting audit timelines while unifying our teams in a single, efficient data environment.” – Komal Thakkar, AVP – Lead, Data Engineering, Avanse Financial Services
Best practices
Based on their experience, Avanse recommends:
Start with a workshop. Validate your specific use cases in a 72-hour technical validation before committing to full migration.
Migrate use cases, not code. Focus on what your analytics accomplish, then implement using cloud-native patterns rather than translating legacy scripts line by line.
Invest in governance early. Implement the data catalog and lineage tracking from day one.
Embrace project-based isolation. Organize around business functions for clear cost allocation and security boundaries.
Document business logic. Use migration as an opportunity to capture undocumented knowledge in the business glossary and dataset descriptions.
Conclusion
Avanse’s migration from an external analytics application to Amazon SageMaker Unified Studio consolidated their analytics stack into a single integrated environment on AWS. By querying data directly in Amazon S3 instead of copying it into the external application, they alleviated their biggest operational bottleneck. Project-based isolation replaced a shared server model, giving each business unit independent compute and clear cost visibility. And centralized governance through SageMaker Catalog and IAM Identity Center gave their compliance team the audit trails they had been missing.
The serverless, usage-based model means Avanse no longer pays for idle capacity. The lakehouse architecture supports new analytics patterns as they emerge, and native integration with AWS services, including generative AI through Amazon Bedrock, positions them to adopt new capabilities as their needs evolve.
Next steps
Start your analytics modernization journey by scheduling a 72-hour technical validation workshop. Contact your AWS account team to discuss your migration approach.
AWS IAM Identity Center provides a web-based access portal that gives your workforce a single place to view their AWS accounts and applications. With the recent launch of IAM Identity Center multi-Region replication, customers can replicate their IAM Identity Center instance across multiple AWS Regions to improve resilience and reduce latency for a globally distributed workforce. As a result, users have a dedicated access portal URL in each Region where Identity Center is replicated, and where administrators need a consistent way to manage these portals to ensure that each user reaches the right one.
This post walks you through building a custom vanity domain (for example, aws.mycompany.com) that serves as a single, memorable entry point for access to IAM Identity Center through the AWS Management Console. The solution uses latency-based routing to automatically redirect users to their nearest healthy access portal endpoint and provides a mechanism to trigger failovers when a Regional Identity Center instance, or the broader AWS Region, is impaired. Because this solution operates outside of Identity Center—at the DNS and load balancer layer—users are transparently redirected to the appropriate Regional access portal URL. Note that the vanity domain itself will not appear in the browser’s address bar.
This guide is structured in three progressive phases: a single-Region redirect, multi-Region latency routing, and automatic health-based failover. You can adopt each phase independently, depending on your organization’s needs.
IAM Identity Center supports multiple access portal URL formats that resolve to the same web portal. The following table summarizes the supported formats in the standard AWS (classic) partition, along with their capabilities:
* Each Regional URL resolves only to its own Region’s portal instance and doesn’t fail over to another Region. Multi-Region here means the URL format is available in every Region where IAM Identity Center is replicated. To route users across Regions dynamically, use the vanity domain approach described in this post.
Note: The ★ highlighted row (https://{idcInstanceId}.portal.{region}.app.aws) is the recommended URL format. It supports both dual-stack (IPv4 and IPv6) and IAM Identity Center multi-Region replication. The awsapps.com formats aren’t always available in newer Regions and don’t support multi-Region capabilities. In additional replicated Regions, the custom alias isn’t supported, and the awsapps.com parent domain isn’t available.
Working with multiple Regional endpoints
As you expand your IAM Identity Center footprint through multi-Region replication, each replicated Region provides a dedicated access portal URL—directing your users to the low-latency entry point closest to their location. A user connecting from Europe and one connecting from Asia Pacific each benefit from their respective Regional endpoint. To deliver the best experience, organizations need a consistent, centrally managed way to direct users to the correct Regional destination; there are a few common approaches you can use to achieve this.
Customers typically start with a single Regional endpoint, which is straightforward to configure, but users in distant Regions experience higher latency, and a Regional incident can affect all users regardless of location. Others maintain per-Region bookmarks or configuration, which gives each user population the right endpoint but requires ongoing IT coordination and clear communication to users.
Custom vanity domains give you full control over DNS routing, health checks, and failover of your access portal connections; all behind a single, brand-aligned domain name (for example, aws.mycompany.com) that users access. A vanity domain makes this start URL memorable and consistent for users, regardless of the underlying IAM Identity Center configuration – a single address to remember and share, compared to maintaining a separate bookmark for each Regional endpoint or managing a growing list of application tiles in your external identity provider. The rest of this guide walks you through how to deploy this solution step by step.
Solution overview
The solution builds a lightweight routing and redirect layer in front of the IAM Identity Center access portal Regional endpoints. The architecture has the following components:
AWS IAM Identity Center – Your existing Identity Center instance
Amazon Route 53 – Manages your vanity domain’s hosted zone, latency-based routing policy, and health checks
AWS Certificate Manager (ACM) – Issues and automatically renews TLS certificates for your vanity domain in each Region
Application Load Balancer (ALB) – Handles HTTP and HTTPS traffic, issuing 302 redirects to the appropriate Regional access portal endpoint
Amazon Application Recovery Controller (ARC) Region switch – Orchestrates Regional failovers by controlling Route 53 health check states, so traffic is automatically shifted away from an unhealthy Region
This guide is structured in three progressive phases. You can adopt each phase incrementally based on your needs:
Phase 1: Sets up the vanity domain with a redirect to a single Regional access portal endpoint. Suitable for organizations with a single-Region Identity Center deployment.
Phase 2: Extends Phase 1 across multiple Regions with latency-based routing, so users are automatically directed to the nearest Regional endpoint. Requires IAM Identity Center multi-Region replication.
Phase 3: Adds an ARC Region switch for managed Regional failover. Without Phase 3, a Regional impairment requires manual DNS updates to redirect traffic. ARC automates this with rehearsable, controlled failover plans.
Figure 1: Solution architecture for custom vanity domain routing with IAM Identity Center.
When a user navigates to aws.mycompany.com, the following happens:
Route 53 evaluates the latency records and routes traffic to the ALB in the lowest-latency healthy Region.
The ALB terminates TLS using an ACM-managed certificate and issues a 302 redirect to the corresponding Regional Identity Center access portal URL.
The user’s browser follows the redirect and loads the access portal directly. Subsequent authentication traffic flows between the browser and AWS—the ALB isn’t in the path.
If you’ve implemented Phase 3, ARC controls Route 53 health check states for each Region. With this configuration, you can stop routing traffic to any Region considered unhealthy.
Prerequisites
Before you begin to build the solution, ensure you have the following in place:
An existing top-level domain (TLD) (for example, mycompany.com).
Phase 1: Redirect to a single predefined access portal endpoint
In this phase, you create the foundational infrastructure: a Route 53 hosted zone, an ACM-managed TLS certificate, and an internet-facing ALB that issues a 302 redirect to your Regional access portal URL. By the end, users who navigate to aws.mycompany.com will be seamlessly redirected to your Identity Center portal.
Create a Route 53 hosted zone for your vanity domain
The hosted zone holds the DNS records that control how aws.mycompany.com resolves. If your top-level domain (mycompany.com) is already registered in Route 53, you create a subdomain hosted zone. If it’s registered with another registrar, you create a public hosted zone and configure name server (NS) delegation manually.
In the AWS Management Console, navigate to Route 53 and choose Hosted zones, then Create hosted zone.
Enter your vanity domain in the Domain name field (for example, aws.mycompany.com).
Select Public hosted zone as the type, then choose Create hosted zone.
Note the four NS records that Route 53 creates for the new hosted zone. You will need these in the next step.
Figure 2: Route 53 hosted zone details
Delegate your subdomain from the parent domain
To make Route 53 authoritative for aws.mycompany.com, you must add an NS record in the parent zone (mycompany.com) pointing to the name servers of the new hosted zone.
If mycompany.com is hosted in Route 53: Open the mycompany.com hosted zone, choose Create record, set the record name to aws, the type to NS, and paste the four NS values from the previous step. Choose Create records.
Ifmycompany.comis hosted elsewhere: Sign in to your registrar’s DNS management console and add an NS record for aws.mycompany.com using the four name server values from the previous step.
Note: DNS propagation for NS delegation can take up to 48 hours, though it typically completes within a few minutes for Route 53-to-Route 53 delegation.
Figure 3: Create a NS record type to delegate your subdomain from the parent domain
Request an ACM certificate
Your ALB requires a TLS certificate for aws.mycompany.com to serve HTTPS traffic. ACM provides free public certificates with automatic renewal.
Go to the Certificate Manager console in the primary Region of IAM Identity Center (for example, us-east-2) and choose Request a certificate.
Select Request a public certificate and choose Next.
Enter your domain name (for example, aws.mycompany.com). Choose Add another name to this certificate and enter your Regional sub-domain (for example, us-east-2.aws.mycompany.com).
Leave other options as defaults (Disable export, DNS validation – recommended, and key algorithm – RSA 2048) and choose Request.
In the certificate details page, choose Create records in Route 53. ACM will automatically add the validation CNAME records to your hosted zone. The certificate status changes to Issued within a few minutes.
Figure 4: Request an ACM certificate for your domain
Create a security group for Identity Center ALB
The security group needs to allow inbound HTTP and HTTPS traffic for both IPv4 and IPv6 from the public internet to make the load balancer reachable.
Go to the Amazon EC2 console, navigate to Security Groups, and choose Create security group.
Enter a Name (for example, identitycenter-global-domain-alb-sg-us-east-2) and Description. Add four rules by choosing Add Rule under Inbound Rules.
Set Type to HTTP, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
Set Type to HTTPS, and Source to Anywhere-IPv4 (0.0.0.0/0) and to Anywhere-IPv6 (::/0).
Choose Add Rule under Outbound Rules and set Type to All traffic and Source to Anywhere-IPv6 (::/0).
Choose Create security group.
Figure 5: ALB security group rules
Create an ALB with an HTTP and HTTPS redirect rule
The ALB is the component that performs the actual redirect to your IAM Identity Center access portal URL. The ALB listener accepts HTTPS requests on port 443 and responds with a 302 redirect to the appropriate Regional Identity Center access portal endpoint.
Go to the Amazon EC2 console, navigate to Load Balancers, and choose Create load balancer. Select Application Load Balancer.
Enter a name for your ALB (for example, identitycenter-redirect-alb).
Configure basic settings: Set the scheme to Internet-facing, IP address type to Dualstack (or IPv4 if IPv6 isn’t supported by your virtual private cloud (VPC)), and select at least two Availability Zones. Ensure that the load balancer is operating in a VPC and subnets that are internet-facing.
Under Security Groups choose theSecurity Group created in the previous step.
Configure an HTTP listener: Add a listener on port 80 (HTTP) with Redirect to URL option. Choose URL parts and set Protocol to HTTPS, Port to 443, and status code to 302 (Found).
Figure 6: Add an HTTP listener during ALB creation
Configure an HTTPS listener: Add a listener on port 443 (HTTPS) with No pre-routing action (default) and Redirect to URL options. Choose Full URL and set the URL to your Regional Identity Center access portal endpoint (For example, https://ssoins-1234567890.portal.<your-region>.app.aws, for this blog the region is us-east-1). Set status code to 302 (Found).
Figure 7: Add an HTTPS listener
Under Default SSL/TLS certificate, select the ACM certificate you created in Step 3.
Note: Make sure to select 302 – Found as the Status code. Selecting 301 – Permanently moved will result in browser caching the redirect URL which will prevent failovers from working correctly until the cache expires.
Create Regional Route 53 records pointing to your ALB
Create a DNS record in your hosted zone that resolves <your-region>.aws.mycompany.com to your ALB.
Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
Set the record name to the AWS Region name (For example: us-east-2) and the record type to A.
Toggle Alias and in the drop down menu Route traffic to, select the alias target to Alias to Application and Classic Load Balancer, select your Region(For example:us-east-2), and select your ALB from the dropdown list.
Leave routing policy as Simple routing, and select the Region (For example:us-east-2) and choose Create records.
Repeat steps 1 through 4 to create AAAA record types.
Figure 8: Route 53 record with simple routing policy
Add latency-based routing configurations
Finally, create a DNS record in your hosted zone that resolves aws.mycompany.com to your Regional Route 53 record.
Open your Route 53 hosted zone for aws.mycompany.com and choose Create record.
Keep the subdomain name for this record as empty, so aws.mycompany.com is the fully qualified record and set the record type to A.
Enable alias: Set the Route traffic to Alias to another record in this hosted zone, and select the hosted zone you created earlier (us-east-2.aws.mycompany.com).
Set Routing Policy to Latency and select the corresponding Region (us-east-2 in this example).
Add a clear name for the Record ID, such as us-east-2--ipv4 as a differentiator and choose Create records.
Repeat the steps1 through 5 to create AAAA record types with us-east-2--ipv6 as the record ID.
Figure 9: Route 53 record with latency-based routing
Test the configuration by navigating to https://aws.mycompany.com in a browser. You should be redirected to your Identity Center access portal. You can also validate using: curl -I https://aws.mycompany.com
Tip: To deploy Phase 1 automatically, download the CloudFormation template from the Deploying with CloudFormation section below.
Phase 2: Automatically route to the nearest Regional access portal endpoint
Phase 2 extends the solution to support IAM Identity Center multi-Region replication by deploying an ALB in each replicated Region and configuring Route 53 latency-based routing. Users are automatically directed to the access portal in the Region that has the lowest network latency from their location, which matches the active-active behavior of the Identity Center access portal itself.
Request ACM certificates in each additional Region
Repeatthe steps from Request an ACM Certificate for each additional Region (for example, us-west-2) where you’ve replicated IAM Identity Center.
Create a security group and an ALB in each additional Region
Repeat the steps from Create a security group for Identity Center ALB and Create an ALB with an HTTP and HTTPS redirect rule in each additional Region. In each ALB’s redirect rule, set the target URL to the access portal endpoint for that specific Region. For example:
us-east-2 ALB redirects to https://ssoins-1234567890.portal.us-east-2.app.aws
us-west-2 ALB redirects to https://ssoins-1234567890.portal.us.west-2.app.aws
Create Regional and latency Route 53 records for the additional Region
For each additional Region where you’ve deployed an ALB and replicated Identity Center, create Regional and latency A and AAAA records as outlined in Create Regional Route 53 records pointing to your ALB and Add latency-based routing configurations.
Tip: To deploy Phase 2 automatically, download the CloudFormation template from the following Deploying with CloudFormation section.
Phase 3: Regional failover using ARC Region switch
Phase 3 introduces Amazon Application Recovery Controller (ARC) Region switch, a fully managed capability that you can use to plan, practice, and orchestrate Regional failovers with confidence. ARC Region switch vends Route 53 health checks directly as part of a Region switch plan. You attach these generated health checks to your Route 53 latency records, and ARC controls their healthy or unhealthy state during plan execution. You can further extend the solution to include custom automation triggered by Amazon CloudWatch alarms or synthetic canaries to update routing control state.
We recommend creating your ARC Region switch plan in the primary Region of your IAM Identity Center for ease of discovery.
Create an active-active instance of ARC Region switch plan
Create an ARC Region switch plan that will orchestrate failovers between your IAM Identity Center Regions and auto-generate the Route 53 health checks you will reference in the next step.
Open the Application Recovery Controllerconsole and choose Region switch in the navigation pane. Select Create Region Switch Plan.
Enter a Plan name (for example, idc-access-portal-failover) and an optional description. Choose Active/Active for Multi-Region recovery approach. Select the Regions where IAM Identity Center is replicated ,including the primary Region.
In the Execution Permission section, enter the Amazon Resource Name (ARN) of the IAM role that ARC will use to update Route 53 health check states during plan execution. If you don’t have an existing role, choose Create a new role to have ARC create one automatically. See AWS Managed Policy: AmazonApplicationRecoveryControllerRegionSwitchPlanExecutionPolicy for information about required permissions.
Choose Create Plan and proceed to Build workflows. Enter optional descriptions and choose Save and continue.
Figure 10: Region switch plan
Set the Workflow type to Activate and set the Region to the corresponding Region (us-east-2 or us-west-2). Within each workflow, choose Add step/Run in Sequence. Choose an execution block to Amazon Route 53 health check execution blog under Networking.
Choose Add and edit. Enter a Step name (for example,Activate Route53 Record Set).
Set the Hosted zone to the hosted zone ID for your aws.mycompany.com domain, and set the Record name to aws.mycompany.com.
Expand Record set identifiers. Choose Add record set identifier and enter a unique identifier for the record set(for example, us-east-2--ipv4 and us-east2--ipv6)and select your Region. Add two record set identifiers (A and AAAA records) for each of your Regions.
Choose Save step.
Repeat steps 5 and 6 for Deactivate and choose Save the plan.
Figure 11: Workflow builder
Choose Save workflows.
Select the newly created plan and choose the Monitoring tab. Note the IDs of the health checks created.
Figure 12: IAM Identity Center access portal plan
Update Route 53 record sets to reference ARC-managed health checks
Associate the ARC-generated health check IDs with the latency-based A and AAAA records you created in Phase 1 and 2. Route 53 uses these health checks—which are now controlled by ARC—to determine which Regions are eligible for DNS resolution. Route 53 still uses latency to choose from the healthy Regions.
Go to the Route 53 console and choose Hosted zones.
Select the hosted zone for aws.mycompany.com.
Find the latency-based A record for us-east-2 that you created in Phase 2, and choose Edit record.
In the Health check section, enable Associate with a health check. In the Health check ID dropdown, select the ARC-generated health check for us-east-2 that you noted at the end of the preceding procedure. Note: Ignore the warning This health check ID doesn’t belong to this AWS account. Make sure you have copied it accurately to use it.
Choose Save changes.
Repeat steps 3, 4, and 5 for A and AAAA records for each of your IAM Identity Center Regions.
Figure 13: Update Route53 record sets
Validate the setup by performing a failover
Validate the end-to-end configuration by executing a controlled failover. Because latency-based routing will always resolve aws.mycompany.com to us-east-2 for users in the primary geography, deactivating us-east-2 is the most direct way to confirm that Route 53 correctly fails over to us-west-2.
Before executing the failover, confirm that aws.mycompany.com is resolving to the us-east-2: curl -I https://aws.mycompany.com Expected: A record pointing to the us-east-2 access portal URL (for example, https://ssoins-1234567890.portal.us-east-2.app.aws:443/).
Go to the Amazon Application Recovery Controller console. In the left navigation pane, choose Region switch.
Select your Region switch plan (idc-access-portal-failover) to open the plan details page.
Choose Execute recovery.
On the Execute plan page, select us-east-2 as the Region to fail out of.
Select the Deactivate action and choose Start execution. ARC sets the us-east-2 health check to unhealthy. Route 53 stops resolving aws.mycompany.com to the us-east-2 ALB and routes traffic to us-west-2 instead.
After a few seconds, confirm the failover has taken effect: curl -I https://aws.mycompany.com Expected: 302 redirect to the us-west-2 IAM Identity Center access portal URL
To fail back, choose Execute plan again. Select us-east-2, select the Activate action and choose Start execution. ARC marks the us-east-2 health check healthy and Route 53 resumes routing traffic to that Region.
Tip: To deploy Phase 3 automatically, download the CloudFormation template from the Deploying with CloudFormation section that follows.
Deploying with CloudFormation
As an alternative to the manual console steps described previously, we provide CloudFormation templates that you can download and deploy for each phase. Each template is self-contained and parameterized, so you only need to provide your environment-specific values (such as your vanity domain name, VPC, and subnet IDs). Download the templates from the following links:
To deploy a template, navigate to the AWS CloudFormation console, choose Create stack, select Upload a template file, and upload the downloaded YAML file. Follow the prompts to provide parameter values and create the stack. For Phase 2, deploy the template once in each additional Region.
Deploy all phases with a single scrip
As an alternative to deploying each CloudFormation template individually, you can use the provided deploy.sh bash script to deploy all three phases in sequence. The script automates stack creation across your primary and additional Region. To get started, download the deployment package, then unzip the file into a local directory:
wget https://aws-security-blog-content.s3.us-east-1.amazonaws.com/public/sample/3536-regional-routing-for-aws-access-portals/Vanity-domains-cfn.zip
unzip  Vanity-domains-cfn.zip
cd Vanity-domains-cfn
Before running the script, open the deploy.sh file and update the following required parameters with your environment-specific values:
TLD – Your top-level domain (for example, mycompany.com)
TLD_HOSTED_ZONE_ID – The Route 53 hosted zone ID for your top-level domain
IDC_SUBDOMAIN – The Identity Center subdomain name (for example, aws)
IDC_INSTANCE_ID – Your IAM Identity Center instance ID (for example, ssoins-1234567890)
PRIMARY_REGION – The primary Region for your Identity Center instance (for example, us-east-2)
ADDITIONAL_REGIONS – The additional Region for multi-Region replication (for example, us-west-2)
After updating the configuration, run the deployment script:
./deploy.sh
The script deploys Phase 1 (single-Region redirect), Phase 2 (multi-Region latency-based routing), and Phase 3 (ARC Region switch failover) in order. Monitor the terminal output for stack creation progress and any errors.
After completing the setup, you can integrate the vanity URL (for example, aws.mycompany.com) directly into your identity provider, such as Okta or Microsoft Entra ID, as a bookmark application or a chiclet URL. By configuring the vanity URL as the bookmark target, users who launch the application from their identity provider dashboard are always redirected to the nearest IAM Identity Center access portal endpoint through latency-based routing. If a Regional impairment occurs and a failover is necessary, administrators can execute an ARC Region switch to deactivate the impaired Region, and users will automatically be redirected to the active Identity Center endpoint without any change to the bookmark URL or end-user experience.
Conclusion
In this post, you learned how to build a custom vanity domain for an AWS IAM Identity Center access portal using Amazon Route 53, AWS Certificate Manager, Application Load Balancer, and an Amazon Application Recovery Controller (ARC) Region switch. The three-phase approach lets you start with a single-Region redirect, progressively add latency-based routing as your IAM Identity Center footprint grows with multi-Region replication, and then introduce an ARC Region switch to gain fully managed, rehearsable Regional failover.
As organizations expand their Amazon Web Services (AWS) footprint, managing secure, scalable, and cost-efficient access across multiple accounts becomes increasingly important. AWS IAM Identity Center offers a centralized, unified solution for managing workforce access to AWS accounts. It simplifies authentication, enhances security, and provides a seamless user sign-in experience to AWS services across diverse environments.
By combining IAM Identity Center permission sets with session tags, organizations can unlock powerful capabilities for fine-grained access control and resource optimization. You can use session tags to pass dynamic attributes from your external identity provider into AWS, enabling more context-aware permissions and better cost visibility. This integration makes it possible to use advanced AWS features such as AWS Glue usage profiles and AWS Systems Manager Session Manager run as to enforce fine-grained access control, so that administrators can dynamically map permissions and runtime configurations based on user attributes passed during federated access.
In this post, I demonstrate how session tags derived from directory group attributes in Microsoft Entra ID can deliver functionality equivalent to AWS Identity and Access Management (IAM) role tags. Using role tags, you can implement attribute-based access control (ABAC) using IAM Identity Center, while maintaining centralized and efficient access management. To demonstrate this, you can configure an AWS Glue usage profile, as described in Introducing AWS Glue usage profiles for flexible cost control, where session tags can be passed through Identity Center and an external identity provider like Microsoft Entra ID. This approach is extensible to other AWS services such as AWS Systems Manager Session Manager (run as) and can also be used with other identity providers.
User authentication and IAM Identity Center Federation flow
The following figure shows the architecture and workflow of the solution.
Figure 1 – User authentication and federation flow between Microsoft Entra and AWS
The user authentication and federation flow includes the following steps:
User accesses application using a browser.
The enterprise application (configured in Azure) initiates authentication.
Microsoft Entra ID handles sign-in.
Users and groups are managed in Entra ID.
A SAML trust is established between Entra ID and IAM Identity Center.
SCIM provisioning syncs users and groups from Entra ID to AWS.
Synced users and groups appear in Identity Center.
Session tags are passed during SAML authentication.
Entra ID can send user attributes (department, role, cost center, project ID, and so on) as SAML attributes.
Identity Center consumes these as session tags, which are used for fine-grained access control and attribute-based access control inside AWS.
Admins define permission sets for users and groups in Identity Center.
Users get federated access to AWS using their Entra ID credentials.
Access to an external identity provider such as Microsoft Entra ID to federate users into AWS. You can enable federated access between Microsoft Entra ID and IAM Identity Center by completing the steps in Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center. They include configuring SAML and SCIM integration between the two systems, testing the SAML connection to help ensure authentication is functioning correctly, and enabling SCIM synchronization to automate user and group provisioning.
Solution implementation
With the prerequisites in place, you’re ready to configure access control through IAM Identity center tags by using the following steps.
Note: For fine-grained access control, you can create custom permission sets by combining AWS managed, customer managed, and inline policies in IAM. In this post, you use AWS managed policies with intentionally broad permissions for simplicity. In production, always follow the principles of least privilege and scope permissions appropriately.
By default, when you create a permission set, the permission set isn’t provisioned (used in any AWS accounts). To provision a permission set in an AWS account, you must assign IAM Identity Center access to users or groups in the account and then apply the permission set to those users and groups. For more information, see Assign user or group access to AWS accounts.
Configure user attributes in Microsoft Entra ID for access control in IAM Identity Center as described in Step 5 of Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center to set up ABAC. Add claim conditions for attribute mapping based on Entra ID group membership. Assign the developer value for users in a corresponding group. This enables logic such as Users in this group receive this profile or All users receive this profile. When using an AWS Glue profile and when making API calls to create AWS Glue resources, admins need to tag the user or role with glue:UsageProfile as the key and the profile name as the value.
Next, sign in to the enterprise application that you created in the previous step, which has SCIM and SAML connections set up to IAM Identity Center:
Figure 3 – An enterprise application created in Microsoft Entra ID
When you’re signed in to your application, select Manage and then Single sign-on in the navigation pane, then select Attributes & Claims.
Figure 4 – Attributes & Claims section in Microsoft Entra ID
Configure the key value pair that will used as session tags by selecting Add new claim.
Figure 5 – Configuring attributes by adding a new claim
For Name, enter AccessControl:<AttributeName>. Replace <AttributeName> with the name of the attribute you are expecting in IAM Identity Center. For this example, use AccessControl:glue:UsageProfile.
In Claim conditions set the following:
User type, select Members
Source, select Attribute.
Value, enter developer (without quotation marks).
Figure 6 – Attribute claim addition in Microsoft Entra using group membership
It’s important to note that the tags are being assigned based on group membership in Microsoft Entra ID. This approach lets you manage access and configuration dynamically without needing to set tags individually for each user. By assigning the tag to a Microsoft Entra ID group, anyone signing in to IAM Identity Center and who is in that group will automatically have the tag value applied to their session.
Test the solution
Now that the required configuration is complete, test the setup using the developer usage profile created as part of the Solution implementation section. Sign in as your user through Microsoft Entra ID using https://myapps.microsoft.com/ and verify the job creation using the following steps mentioned.
To verify successful job creation:
Open the AWS Glue console using the developer usage profile.
In the navigation pane, choose ETL jobs.
Select Script editor, then choose Create script.
Create a new job using the values you want to validate.
The green banner at the top of the screen should say Successfully updated job.
Figure 7 – Successful AWS Glue job creation with configured parameters for the developer usage profile
Validation using AWS CloudTrail
Examine the AssumeRoleWithSAML event using AWS Cloudtrail. Use the following steps to verify the sequence of events.
Navigate to the CloudTrail console.
Select Event history.
In the Lookup attributes dropdown, select Event name.
Set the event name to AssumeRoleWithSAML.
Open a relevant event and inspect the requestParameters section.
Confirm that the expected session tags appear under PrincipalTags.
Figure 8 – ABAC tags passed during the role assumption
Using session tags for other use cases
The concepts discussed in this post can be extended to configure AWS Systems ManagerSession ManagerRun As support for federated users using session tags. By default, Session Manager launches sessions using a system-generated ssm-user account. For Linux instances, you can optionally configure sessions to run as a specific OS-level user through Session Manager preferences. You can configure your identity provider to pass the user attribute (AccessControl: SSMSessionRunAs and name of an OS user account for the key value during federation and the session will be tagged using the attribute value.
Clean up
To avoid incurring future charges, delete any resources created during this walkthrough if they’re no longer needed:
Remove the IAM Identity Center instance and clean up the associated enterprise application in Microsoft Entra.
Delete the AWS Glue usage profile.
Remove any other AWS resources you provisioned for testing the solution.
Conclusion
In this post, you learned how to federate access to AWS using AWS IAM Identity Center and SAML 2.0 identity providers like Microsoft Entra ID, enabling a secure, scalable, and centralized approach to managing user access across multiple AWS accounts. By using permission sets, reserved IAM roles, and session tags, organizations can implement fine-grained ABAC without the complexity of managing individual IAM users or static roles.
As cloud environments become more complex, adopting modern identity federation and ABAC through IAM Identity Center helps security teams maintain control while providing users with seamless, context-aware access to the resources they need.
Amazon Redshift is a fully managed, petabyte-scale cloud-based data warehouse that you can use to scale analytics workloads effortlessly. As organizations expand their analytics capabilities across multiple business units, they need streamlined approaches for defining and managing fine-grained permissions for each warehouse. Many organizations use external identity providers (IdPs) like Microsoft Entra ID, Okta, or Ping to manage workforce identities centrally and need streamlined data warehouse integration with consistent access controls. We address these challenges by introducing Amazon Redshift federated permissions with AWS IAM Identity Center integration so that you can define security policies once and automatically enforce them across the warehouses in your account.
Amazon Redshift federated permissions are now supported with IAM Identity Center across multiple AWS Regions, where you can use identities from supported identity provider (IdP) such as Microsoft Entra ID, Okta, Ping Identity, or OneLogin across supported AWS Regions with IAM Identity Center. This enables you to align with business requirements including resiliency and proximity to users. You can now extend IAM Identity Center from your primary AWS Region to additional Regions of your choice based on your data residency requirements. In that region, you can get horizontal multi-warehouse scalability by adding new warehouses using Amazon Redshift federated permissions across multiple warehouses. With Redshift federated permissions, you define data permissions once from any Redshift warehouse in that region and automatically enforce them across all warehouses in the account in that region.
This post provides a comprehensive technical walkthrough for implementing Amazon Redshift federated permissions with AWS IAM Identity Center to help achieve scalable data governance across multiple data warehouses. It demonstrates a practical architecture where an Enterprise Data Warehouse (EDW) serves as the producer data warehouse with centralized policy definitions, helping automatically enforce security policies to consuming Sales and Marketing data warehouses without manual reconfiguration. You will learn how to do the following:
Configure IAM Identity Center connections for both data sharing producers and consumers
Register Amazon Redshift serverless namespaces with AWS Glue Data Catalog
Set up trusted identity propagation (TIP)
Create and attach Dynamic data masking policies to help protect personally identifiable information (PII) like customer dates of birth
Implement row-level security policies to control data visibility based on user roles
Map IdP groups to Amazon Redshift database roles for seamless access management
Prerequisites
Before you begin, verify that you have the following:
Review the blog post to understand the setup process of AWS IAM Identity Center integration with Amazon Redshift Query Editor v2
IAM Identity Center enabled in your AWS account, with users and groups created as listed under Solution overview section of User access (figure 2)
As an Amazon Redshift superuser, grant CONNECT, CREATE TABLE, INSERT, SELECT, and sys:secadmin permissions to AWSIDC:awssso-admin database role
An IAM role for IAM Identity Center access:
Step 1:Create an IAM policy for Amazon Redshift access. To integrate Amazon Redshift with IAM Identity Center, create an IAM policy (for example, aws-idc-policy) in the account where your Amazon Redshift data warehouse exists:
Step 2: Create the IAM role. Create an IAM role (Amazon Redshift – Customizable) in the account where your Amazon Redshift data warehouse exists (for example, IAMIDCRedshiftRole).
Step 3: Attach IAM policies to the role. Attach the following two IAM policies to the previously mentioned role:
Note:AmazonRedshiftFederatedAuthorization is a managed policy that provides the necessary permissions for running queries with Amazon Redshift federated authorization.
Attach above IAMIDCRedshiftRole IAM role to all Redshift serverless endpoints
Solution overview
The following architecture diagram demonstrates federated permissions in a multi-warehouse environment, enabling scalable data governance across Amazon Redshift warehouses by automatically enforcing security policies.
Figure 1: Sample architecture diagram
User access
Users can access data warehouses through Amazon Redshift Query Editor v2, third-party SQL editors (such as DBeaver and SQL Workbench), or custom client applications. The access methods help provide consistent security enforcement.
Figure 2: Solution overview flow
AWS IAM Identity Center integration
IAM Identity Center provides centralized authentication with single sign-on capabilities and automatically assigns role-based permissions based on organizational roles. This identity federation links corporate identities directly to AWS resources, making sure that authentication occurs at the identity layer before warehouse access.
Multi-warehouse architecture
This architecture uses three distinct data warehouses that serve different business functions while sharing centralized security policies.
Enterprise Data Warehouse (EDW)
The EDW serves as the central repository for enterprise data. In this architecture, customer and product data are stored in the Customer Profile Database (CPD), where administrators define two critical security policies:
Dynamic data masking (DDM) – Masks sensitive customer Date of Birth (DOB) fields for both Sales Analyst and Marketing Analyst roles, helping protect personally identifiable information (PII) while allowing analytical work
Row-level security (RLS) – Controls product visibility based on user roles. Sales Analysts view only launched products, while Marketing Analysts view both launched and planned products
The EDW registers with the AWS Glue Data Catalog, creating a unified metadata repository that makes data discoverable across the warehouses in the account. This registration establishes the foundation for federated permissions, enabling automatic policy propagation.
Sales data warehouse
When Sales Analysts query customer and product tables, the system automatically enforces policies defined in the EDW through federated permissions. The registered namespace from the EDW automatically mounts as an external database, alleviating the need to recreate or reattach policies. Customer DOB fields appear masked, and only launched products are visible without additional configurations.
Marketing data warehouse
The Marketing Data Warehouse automatically inherits and enforces EDW security policies. Customer DOB fields remain masked to help protect PII, but with RLS policies, Marketing Analysts can view both launched and planned products. This provides the broader visibility needed for marketing planning. This differentiated access control is automatically enforced based on user roles.
Walkthrough
In this walkthrough, you create two Amazon Redshift IAM Identity Center (IDC) connections:
Data sharing producer identity center connection – Assigned to the edw-wg Amazon Redshift serverless workgroup
Data sharing consumer identity center connection – Assigned to the cpd-sales-wg and cpd-marketing-wg Amazon Redshift serverless workgroups
Set up IDC connections for Amazon Redshift federated permissions
In this section, you configure the IAM Identity Center connections that enable federated authentication across your warehouses. You will create separate connections for the producer (policy-defining) warehouse and consumer warehouses.
Configure Amazon Redshift data sharing producer IDC connection
Choose Actions, and then select Register with AWS Glue Data Catalog.
Choose Register with Amazon Redshift federated permissions.
Choose Amazon Redshift federated permissions using AWS IAM Identity Center.
Choose Register.
Figure 5: Amazon Redshift data warehouse registration with Glue Data Catalog
Figure 6: Amazon Redshift data warehouse registration with Glue Data Catalog
Note: IAM Identity Center managed application ARN Data sharing producer IDC connection created would be used.
Configure Amazon Redshift data sharing consumer IDC connection for existing serverless namespace
For cpd-sales-wg and cpd-marketing-wg serverless workgroups, gather the following information from your registered IAM Identity Center connection:
IAM Identity Center display name
Identity provider namespace
IAM Identity Center managed application ARN
IAM role for IAM Identity Center access
Run the following SQL command as a database administrator to enable the integration:
CREATE IDENTITY PROVIDER "<IAM Identity Center display name>" TYPE AWSIDC
NAMESPACE '<Identity provider namespace>'
APPLICATION_ARN '<IAM Identity Center managed application ARN>'
IAM_ROLE '<IAM role for IAM Identity Center access>';
To modify an existing identity provider, use the ALTER IDENTITY PROVIDER command:
ALTER IDENTITY PROVIDER "<IAM Identity Center display name>"
NAMESPACE '<Identity provider namespace>';
ALTER IDENTITY PROVIDER "<IAM Identity Center display name>"
IAM_ROLE default | '<IAM role for IAM Identity Center access>';
Data preparation and access setup from producer
In this section, you create the customer and product tables, load sample data, create DDM and RLS policies, attach the policies to database roles and grant SELECT permissions to the roles.
Prepare data on EDW
Connect to the EDW data warehouse as an IDC Admin user and run the following SQL commands.
INSERT INTO product
VALUES
  ('AAAAAAAAAFNPEAAA','At least concerned authors adopt just brown, federal',7.12,4.12,'Jewelry','launched'),
  ('AAAAAAAAOAAGDAAA','Complex services may not find totally changing accountants. Tiny, available ministers could not know always systems. Hot, male speakers discer',8.08,5.49,'Shoes','planned'),
  ('AAAAAAAAMJJMCAAA','Rows could prevent political, old duties. Just international stairs would regret police. Conditions discard always interesting, warm years. Present jobs shall take nearby relatively dreadful',8.18,5.31,'Jewelry','launched'),
  ('AAAAAAAAKLBLBAAA','Suddenly external sentences believe then by the assets. Simultaneously young feet could not probe separately shortly new men. Forms work again individuals. Images',17.96,7.9,'Shoes','launched'),
  ('AAAAAAAAMBKMCAAA','Clubs see finally materials. Significant objectives sell fairly left, civil power',3.18,3.84,'Books','launched'),
  ('AAAAAAAACPCAAAAA','Perhaps past preferences tell rather to a accounts. Very common feet can command never available final years; minutes expect recent, due employers. Altogether english shoes',9.84,0.19,'Electronics','planned'),
  ('AAAAAAAAFOIABAAA','More responsible characters go left factors. Championships shall stand twice new, important shows. Books could receive too able, national pounds. Central',3.55,2.2,'Books','launched'),
  ('AAAAAAAAKGBIAAAA','High, political changes shall not',9.55,5.25,'Electronics','launched');
Create the masking policy for customer date of birth:
CREATE MASKING POLICY mask_cust_dob
WITH (date_of_birth VARCHAR(32))
USING (sha2(date_of_birth, 256)::TEXT);
Create RLS policies for product launch status:
CREATE RLS POLICY product_launch_status
WITH (launch_status VARCHAR(50))
USING (launch_status = 'launched');

CREATE RLS POLICY product_launch_status_all
WITH (launch_status VARCHAR(50))
USING (launch_status IN ('launched','planned'));
Create Amazon Redshift DB roles for Sales and Marketing groups
Create the database roles:
CREATE ROLE "AWSIDC:awssso-sales";
CREATE ROLE "AWSIDC:awssso-marketing";
Attach masking policies
Attach the masking policy to both roles:
ATTACH MASKING POLICY mask_cust_dob
ON dev.public.customer (date_of_birth)
TO ROLE "AWSIDC:awssso-marketing";
ATTACH MASKING POLICY mask_cust_dob
ON dev.public.customer (date_of_birth)
TO ROLE "AWSIDC:awssso-sales";
Attach RLS policies and enable RLS on product table
Attach the RLS policies and enable row-level security:
ATTACH RLS POLICY product_launch_status
ON dev.public.product
TO ROLE "AWSIDC:awssso-sales";
ATTACH RLS POLICY product_launch_status_all
ON dev.public.product
TO ROLE "AWSIDC:awssso-marketing";
ALTER TABLE dev.public.product ROW LEVEL SECURITY ON;
Grant access to tables to roles
Grant SELECT permissions to both roles:
GRANT SELECT ON dev.public.customer TO ROLE "AWSIDC:awssso-sales";
GRANT SELECT ON dev.public.customer TO ROLE "AWSIDC:awssso-marketing";
GRANT SELECT ON dev.public.product TO ROLE "AWSIDC:awssso-sales";
GRANT SELECT ON dev.public.product TO ROLE "AWSIDC:awssso-marketing";
Connect to SALES data warehouse using IAM Identity Center
To connect as a Sales Analyst:
Connect to cpd-sales-wg using the IAM Identity Center connection type as user sales-analyst, and then choose Continue.
Choose sales-analyst, and then choose Next.
Enter your password, and then choose Sign in.
Enter your MFA code, and then choose Sign in.
You are now connected to Amazon Redshift Query Editor V2 with a successful connection to cpd-sales-wg as sales-analyst.
Figure 7: Connect to Sales data warehouse as IDC user
Query shared data as Sales Analyst
Query the customer table with dynamic data masking applied:
SELECT * FROM "dev@edw-ns"."public"."customer";
You can successfully access the customer table, but the sensitive information in the date_of_birth column is encrypted.
Figure 8: Result set of customer table
Query the product table with row-level security enabled:
SELECT * FROM "dev@edw-ns"."public"."product";
You can successfully access the product table, but only view data for products with a launch_status value of launched.
Figure 9: Result set of product table
Note: To connect to the data sharing producer onboarded to Amazon Redshift federated permissions as an IDC user, a superuser is required to provide a CONNECT privilege to the IDC user trying to connect. For more information about how to grant the CONNECT privileges to the user, see Connect privileges in the Amazon Redshift Database Developer Guide.
Connect to Marketing data warehouse using IAM Identity Center
To connect as a Marketing Analyst:
Connect to cpd-marketing-wg using the IAM Identity Center connection type as user marketing-analyst, and then choose Continue.
Choose marketing-analyst, and then choose Next.
Enter your password, and then choose Sign in.
Enter your MFA code, and then choose Sign in.
You are now connected to Amazon Redshift Query Editor V2 with a successful connection to cpd-marketing-wg as marketing-analyst.
Figure 10: Connect to Marketing data warehouse as IDC user
Query shared data as Marketing Analyst
Query the customer table with dynamic data masking applied:
SELECT * FROM "dev@edw-ns"."public"."customer";
You can successfully access the customer table, but the sensitive information in the date_of_birth column is encrypted.
Figure 11: Result set of customer table
Query the product table with row-level security enabled:
SELECT * FROM "dev@edw-ns"."public"."product";
You can successfully access the product table and view data for products with launch_status values of both launched and planned.
Figure 12: Result set of product table
Additional resources
For more information about implementing federated permissions in your environment, see the following resources:
Consistent security enforcement – Policies apply uniformly across the warehouses and access methods
Seamless identity integration – Single sign-on with existing identity providers through trusted identity propagation and role-based access control
Conclusion
This post showed you how Amazon Redshift federated permissions with AWS IAM Identity Center integration helps streamline multi-warehouse data governance by centralizing security policy management. You define dynamic data masking and row-level security policies once in a central Enterprise Data Warehouse, and they automatically enforce across the connected data warehouses in the same account and Region.
With this feature, you can replicate your workforce identities, permission sets, and other metadata in your organization instance of IAM Identity Center connected to an external identity provider (IdP), such as Microsoft Entra ID and Okta, from its current primary Region to additional Regions for improved resiliency of AWS account access.
You can also deploy AWS managed applications in your preferred Regions, close to application users and datasets for improved user experience or to meet data residency requirements. Your applications deployed in additional Regions access replicated workforce identities locally for optimal performance and reliability.
When you replicate your workforce identities to an additional Region, your workforce gets an active AWS access portal endpoint in that Region. This means that in the unlikely event of an IAM Identity Center service disruption in its primary Region, your workforce can still access their AWS accounts through the AWS access portal in an additional Region using already provisioned permissions. You can continue to manage IAM Identity Center configurations from the primary Region, maintaining centralized control.
Enable IAM Identity Center in multiple Regions To get started, you should confirm that the AWS managed applications you’re currently using support customer managed AWS Key Management Service (AWS KMS) key enabled in AWS Identity Center. When we introduced this feature in October 2025, Seb recommended using multi-Region AWS KMS keys unless your company policies restrict you to single-Region keys. Multi-Region keys provide consistent key material across Regions while maintaining independent key infrastructure in each Region.
Before replicating IAM Identity Center to an additional Region, you must first replicate the customer managed AWS KMS key to that Region and configure the replica key with the permissions required for IAM Identity Center operations. For instructions on creating multi-Region replica keys, refer to Create multi-Region replica keys in the AWS KMS Developer Guide.
Go to the IAM Identity Center console in the primary Region, for example, US East (N. Virginia), choose Settings in the left-navigation pane, and select the Management tab. Confirm that your configured encryption key is a multi-Region customer managed AWS KMS key. To add more Regions, choose Add Region.
You can choose additional Regions to replicate the IAM Identity Center in a list of the available Regions. When choosing an additional Region, consider your intended use cases, for example, data compliance or user experience.
If you want to run AWS managed applications that access datasets limited to a specific Region for compliance reasons, choose the Region where the datasets reside. If you plan to use the additional Region to deploy AWS applications, verify that the required applications support your chosen Region and deployment in additional Regions.
Choose Add Region. This starts the initial replication whose duration depends on the size of your Identity Center instance.
After the replication is completed, your users can access their AWS accounts and applications in this new Region. When you choose View ACS URLs, you can view SAML information, such as an Assertion Consumer Service (ACS) URL, about the primary and additional Regions.
How your workforce can use an additional Region AWS Identity Center supports SAML single sign-on with external IdPs, such as Microsoft Entra ID and Okta. Upon authentication in the IdP, the user is redirected to the AWS access portal. To enable the user to be redirected to the AWS access portal in the newly added Region, you need to add the additional Region’s ACS URL to the IdP configuration.
The following screenshots show you how to do this in the Okta admin console:
Then, you can create a bookmark application in your identity provider for users to discover the additional Region. This bookmark app functions like a browser bookmark and contains only the URL to the AWS access portal in the additional Region.
You can also deploy AWS managed applications in additional Regions using your existing deployment workflows. Your users can access applications or accounts using the existing access methods, such as the AWS access portal, an application link, or through the AWS Command Line Interface (AWS CLI).
To learn more about which AWS managed applications support deployment in additional Regions, visit the IAM Identity Center User Guide.
Things to know Here are key considerations to know about this feature:
Consideration – To take advantage of this feature at launch, you must be using an organization instance of IAM Identity Center connected to an external IdP. Also, the primary and additional Regions must be enabled by default in an AWS account. Account instances of IAM Identity Center, and the other two identity sources (Microsoft Active Directory and IAM Identity Center directory) are presently not supported.
Operation – The primary Region remains the central place for managing workforce identities, account access permissions, external IdP, and other configurations. You can use the IAM Identity Center console in additional Regions with a limited feature set. Most operations are read-only, except for application management and user session revocation.
Monitoring – All workforce actions are emitted in AWS CloudTrail in the Region where the action was performed. This feature enhances account access continuity. You can set up break-glass access for privileged users to access AWS if the external IdP has a service disruption.
SageMaker Unified Studio provides an integrated experience to use your data and tools for analytics and AI. You can use SageMaker Unified Studio to discover your data and put it to work using familiar AWS analytics and machine learning (ML) services for model development, generative AI, big data processing, and SQL analytics, assisted by Amazon Q Developer. By default, SageMaker domains support AWS Identity and Access Management (IAM) user credentials. You can also enable access to SageMaker domains in SageMaker Unified Studio for users with single sign-on (SSO) with IAM Identity Center and direct SAML integration with SageMaker Unified Studio.
Users can access SageMaker Unified Studio with their existing corporate credentials. With IAM Identity Center, administrators can connect their existing external IdPs and continue to manage users and groups in those existing identity systems, which can then be synchronized with IAM Identity Center using System for Cross-domain Identity Management (SCIM).In this post, we show how to set up workforce access with SageMaker Unified Studio using Ping Identity as an external IdP with IAM Identity Center.
In this post, we show how to set up workforce access with SageMaker Unified Studio using Ping Identity as an external IdP with IAM Identity Center.
Solution overview
We walk through the following high-level steps to implement this solution:
Enable IAM Identity Center.
Create a SageMaker Unified Studio domain.
Set up your IdP (for this example, Ping Identity).
Connect Ping Identity and IAM Identity Center.
Set up automatic provisioning of users and groups in IAM Identity Center.
Configure SageMaker Unified Studio SSO user access.
Prerequisites
For this walkthrough, you should have the following prerequisites:
An AWS account with IAM Identity Center enabled. It is recommended to use an organization-level IAM Identity Center instance for best practices and centralized identity management across your AWS organization.
On the SageMaker console, go to the domain details and copy the Amazon Resource Name (ARN) under Domain ARN. You will use this value when you add your trust policy and when you connect your IAM IdP to your Ping Identity instance.
Set up your IdP (Ping Identity)
In this section, we walk through the procedure to set up your IdP (for this example, Ping Identity).
Create an environment in Ping Identity
Complete the following steps to create an environment for Ping Identity:
In the Tailor your experiences pop-up, choose Skip.
Create a group in Ping Identity
Complete the following steps to create a group in Ping Identity:
On the Environments page, choose Manage Environments.
In the navigation pane, choose Directory, then choose Groups.
Choose the plus sign to add a group.
For Group Name, enter sagemaker
For Description, enter an optional description (for example, Amazon SageMaker Unified Studio).
For Population, choose Default.
Choose Save.
On the Roles tab for the sagemaker group, assign the Environment Admin role to the group.
Create a user in Ping Identity
Complete the following steps to create a user:
In the navigation pane, choose Directory, then choose Users.
Choose the plus sign to create a user.
Provide values for Given name, Family name, Username, and Email.
For Password, choose First time password.
Choose Save.
You can add more users as needed.
Assign group to user
Complete the following steps to assign your group to your user:
In the navigation pane, choose Directory, then choose Groups.
Choose the sagemaker group you created.
On the Users tab, choose the plus sign to add a user.
Add the user you created.
Connect Ping Identity and IAM Identity Center
To configure the integration between Ping Identity and IAM Identity Center, you need access to both management consoles. Although Ping Identity’s application catalog includes IAM Identity Center, we recommend configuring a standard SAML application for greater control over settings and attribute mappings.
Complete the following steps:
Go to the Ping Identity environment you created and choose Applications in the navigation pane.
Choose the plus sign to add an application:
For Application name, enter a name (for this example, we use unifiedstudio).
For Description, enter an optional description.
For Application Type, choose SAML Application.
Choose Configure.
Sign in to the IAM Identity Center console as a user with administrative privileges.
In the navigation pane, choose Settings to update your settings:
On the Identity source tab, choose Change identity source on the Actions dropdown menu.
For Choose identity source, select External identity provider, then choose Next.
In the Service provider metadata section, choose Download metadata file to download the IAM Identity Center metadata file.
You will use this service provider metadata file in the next step when you connect Ping Identity with IAM Identity Center.
Return to the Ping Identity console and the SAML application page.
In the SAML Configuration section, select Import Metadata, upload the metadata file you downloaded, then choose Save.
On the Overview tab of the application page, choose Download Metadata under Connection details to download the Ping Identity IdP metadata. You will use this for the SAML configuration in IAM Identity Center to set up Ping Identity as an IdP in the next step.
Return to the IAM Identity Center console and continue configuring your identity source:
In the Identity provider metadata section, choose Choose file under IdP SAML metadata, upload the metadata file you downloaded from Ping Identity, then choose Next.
Choose Accept to accept the disclaimer.
Choose Change identity source.
Return to the Ping Identity console to complete the SAML configuration.
On the Configuration tab, choose the edit icon to update the configuration:
For Sign, choose Sign Assertion & Response.
For Subject Name ID, enter urn:oasis:names:tc:SAML:1.1:nameid-format:emailAddress.
For Assertion Validity Duration, enter 300.
Leave the remaining values as default.
On the Attributes tab, choose the edit icon.
Choose +Add to add two attribute mappings:
Map the attribute saml-subject to Username, and leave Name format as default.
Map the attribute https://aws.amazon.com/SAML/Attributes/PrincipalTag:Email to Email Address, and set Name format to Unspecified.
Choose Save.
On the PingOnePolicies tab, select Single Factor, then choose Save. This post uses single-factor authentication for demonstration purposes only. In your environments, follow your organization’s security standards and governance framework.
On the Access tab, search for the sagemaker group under Group Membership Policy, and assign the unifiedstudio SAML application to the group.
Enable the application.
Set up automatic provisioning of users and groups from Ping Identity into IAM Identity Center
To configure the automatic provisioning of users and groups between Ping Identity and IAM Identity Center through SCIM, you must have access to both management consoles. Complete the following steps:
On the IAM Identity Center console, choose Settings in the navigation pane.
In the Automatic provisioning section, choose Enable.
This enables automatic provisioning in IAM Identity Center and displays the necessary SCIM endpoint and access token information.
In the Inbound automatic provisioning dialog box, copy the values for SCIM endpoint and Access token, then choose Close. You will use these values to configure provisioning in Ping Identity in the next step.
This completes the setup process in IAM Identity Center.
Log in to the Ping Identity console.
In the navigation pane, choose Integrations, then choose Provisioning.
Choose the plus sign to add a new connection.
For Choose a connection type, choose Select next to Identity Store.
Provide a name (for this example, we use Identitycenter) and an optional description, then choose Next.
Under Configuration Authentication, provide the following configuration:
For SCIM BASE URL, enter the SCIM endpoint from IAM Identity Center.
For Authentication Method, choose OAuth 2 Bearer Token.
For Oauth Access Token, enter the access token from IAM Identity Center.
For Auth Type Header, choose Bearer (default option).
Choose Test Connection to validate the connection between Ping Identity and IAM Identity Center, then choose Next.
Under Configuration Preference, provide the following configuration:
For User Filter Expression, enter userName Eq “%s”.
For Group Membership Handling, select Merge.
Leave the remaining settings as default and choose Save.
On the Provisioning tab, choose the plus sign, then choose New Rule to create a rule for the SCIM connection.
Enter a name (for this example, unifiedstudio) and an optional description, then choose Create Rule.
Under the newly created rule, choose the plus sign next to Available Connections to add the connection identitycenter, then choose Save.
Edit the user filter:
For Attribute, choose Enabled.
For Operator, choose Equals.
For Value, choose true.
Choose Save.
Choose the edit icon next to Attribute Mapping and set the attribute mappings as shown in the following screenshot:
Delete the Primary Phone attribute mapping because it’s optional in AWS. Leaving this field blank can cause Ping Identity’s SCIM connector to generate errors during user provisioning.
Add a new attribute called Username under PingOne Directory and then map to displayName under Identitycenter.
Under Group Provisioning, choose the sagemaker group if you want to sync all sagemaker group users with auto provisioning.
In the pop-up, select I understand and want to continue, then choose Save.
On the Provisioning page, choose the Connections tab.
Enable the SCIM connection Identitycenter and rule unifiedstudio.
This completes the SCIM setup process between Ping Identity and IAM Identity Center.
Configure SageMaker Unified Studio SSO user access
Complete the following steps to configure SSO user access to SageMaker Unified Studio for your SageMaker domain:
On the SageMaker console, choose Domains in the navigation pane.
Choose the domain for which you want to configure SAML user access.
On the domain details page, you can find the SSO configuration in two locations:
From the main domain view, choose Configure next to Configure SSO user access.
Alternatively, scroll down to the User management tab and choose Configure SSO user access.
On the Choose user authentication method page, select IAM Identity Center, then choose Next.
For Choose user and group assignment method, choose from the following options, then choose Next:
Require assignments: Users and groups must be explicitly added to the domain to gain access. This provides more granular control over who can access the domain.
Do not require assignments: All authorized Ping Identity users and groups can access this domain if they have been assigned to the SAML application in Ping Identity.
For either option, users or groups must have access to the Ping Identity SAML application (unifiedstudio in this example) to authenticate successfully.
On the Review and save page, review your choices and choose Save. These settings can’t be changed after you save them.
If you’ve chosen to require assignments, use the Add users and groups section to add SAML users and groups to your domain.
Now, users will be able to access SageMaker Unified Studio using the domain URL with their SSO credentials.
You can explore different projects for your users and assign those projects based on your IdP user groups for fine-grained access controls. For example, you can create different SAML user groups based on their job function in Ping Identity, then assign those Ping Identity groups to the unifiedstudio SAML application in Ping Identity, and then assign those Ping Identity SAML groups to their respective project profiles in SageMaker Unified Studio. To assign project profiles for their respective groups, choose the Project profiles tab and choose your project profile. On the Authorized users and groups page, choose Add, then choose SSO groups. Choose Add users and groups button to complete the project profile assignment.
Validate access with Ping Identity users
Complete the following steps to validate access:
On the SageMaker domain details page, choose the link for the SageMaker Unified Studio URL.
Log in with your user credentials. After successful login, you will be redirected to the SageMaker Unified Studio home page. Here, you can explore different projects to your users and assign those projects based on your SAML user groups for fine-grained access control.
To assign an authorization policy, those Govern and then Domain units.
Choose your SageMaker domain, then choose a suitable authorization policy. For this example, we choose Project creation policy.
Choose Add policy grant to assign user groups or users to their respective project profiles.
You have successfully federated SageMaker Unified Studio with Ping Identity as an IdP with IAM Identity Center. You can connect to SageMaker Unified Studio by using your Ping Identity credentials.
Clean up
After you test out this solution, remember to delete the resources you created to avoid incurring future charges. For instructions to delete your SageMaker Unified Studio domain, refer to Delete domains. If you want to delete your Ping Identity account, reach out to Ping Identity for assistance.
Conclusion
In this post, we demonstrated how to set up Ping Identity as an IdP over SAML authentication for SageMaker Unified Studio access through IAM Identity Center federation. To learn more, refer to the Amazon SageMaker Unified Studio User Guide, which provides guidance on how to build data and AI applications using SageMaker.
When you enable IAM Identity center, it provides an access portal for workforce users to access their AWS applications and accounts either by signing in to the access portal using a URL or by using a bookmark for the application URL. In either case, the access portal handles user authentication before granting access to applications and accounts. Supporting both IPv4 and IPv6 connectivity to the access portal helps facilitate seamless access for clients, such as browsers and applications, regardless of their network configuration.
The launch of IPv6 support in IAM Identity Center introduces new dual-stack endpoints that support both IPv4 and IPv6, so that users can connect using IPv4, IPv6, or dual-stack clients. Current IPv4 endpoints continue to function with no action required. The dual stack capability offered by Identity Center extends to managed applications. When users access the application dual-stack endpoint, the application automatically routes to the Identity Center dual-stack endpoint for authentication. To use Identity Center from IPv6 clients, you must direct your workforce to use the new dual-stack endpoints, and update configurations on your external identity provider (IdP), if you use one.
In this post, we show you how to update your configuration to allow IPv6 clients to connect directly to IAM Identity Center endpoints without requiring network address translation services. We also show you how to monitor which endpoint users are connecting to. Before diving into the implementation details, let’s review the key phases of the transition process.
Transition overview
To use IAM Identity Center from an IPv6 network and client, you need to use the new dual-stack endpoints. Figure 1 shows what the transition from IPv4 to IPv6 over dual-stack endpoints looks like when using Identity Center. The figure shows:
A before state where clients use the IPv4 endpoints.
The transition phase, when your clients use a combination of IPv4 and dual-stack endpoints.
After the transition is complete, your clients will connect to dual-stack endpoints using their IPv4 or IPv6, depending on their preferences.
Figure 1: Transition from IPv4-only to dual-stack endpoints
Prerequisites
You must have the following prerequisites in place to enable IPv6 access for your workforce users and administrators:
Work with your network administrators to update the configuration of your firewalls and gateways and to verify that your clients, such as laptops or desktops, are ready to accept IPv6 connectivity. If you have already enabled IPv6 connectivity for other AWS services, you might be familiar with these changes. Next, implement the two steps that follow.
Step 1: Update your IdP configuration
You can skip this step If you don’t use an external IdP as your identity source.
In this step, you update the Assertion Consumer Service (ACS) URL from your IAM Identity Center instance into your IdP’s configuration for single sign-on and the SCIM configuration for user provisioning. Your IdP’s capability determines how you update the ACS URLs. If your IdP supports multiple ACS URLs, configure both IPv4 and dual-stack URLs to enable a flexible transition. With that configuration, some users can continue using IPv4-only endpoints while others use dual-stack endpoints for IPv6. If your IdP supports only one ACS URL, to use IPv6 you must update the new dual-stack ACS URL in your IdP and transition all users to using dual-stack endpoints. If you don’t use an external IdP, you can skip this step and go to the next step.
Update both the SAML single sign-on and the SCIM provisioning configurations:
Update the single sign-on settings in your IdP to use the new dual-stack URLs. First, locate the URLs in the AWS Management Console for IAM Identity Center.
Choose Settings in the navigation pane and then select Identity source.
Choose Actions and select Manage authentication.
in Under Manage SAML 2.0 authentication, you will find the following URLs under Service provider metadata:
AWS access portal sign-in URL
IAM Identity Center Assertion Consumer Service (ACS) URL
IAM Identity Center issuer URL
If your IdP supports multiple ACS URLs, then add the dual-stack URL to your IdP configuration alongside existing IPv4 one. With this setting, you and your users can decide when to start using the dual-stack endpoints, without all users in your organization having to switch together.
Figure 2: Dual-stack single sign-on URLs
If your IdP does not support multiple ACS URLs, replace the existing IPv4 URL with the new dual-stack URL, and switch your workforce to use only the dual-stack endpoints.
Update the provisioning endpoint in your IdP. Choose Settings in the navigation pane and under Identity source, choose Actions and select Manage provisioning. Under Automatic provisioning, copy the new SCIM endpoint that ends in api.aws. Update this new URL in your external IdP.
Figure 3: Dual-stack SCIM endpoint URL
Step 2: Locate and share the new dual-stack endpoints
Your organization needs two kinds of URLs for IPv6 connectivity. The first is the new dual-stack access portal URL that your workforce users use to access their assigned AWS applications and accounts. The dual-stack access portal URL is available in the IAM Identity Center console, listed as the Dual-stack in the Settings summary (you might need to expand the Access portal URLs section, shown in Figure 4).
This dual-stack URL ends with app.aws as its top-level domain (TLD). Share this URL with your workforce and ask them to use this dual-stack URL to connect over IPv6. As an example, if your workforce uses the access portal to access AWS accounts, they will need to sign in through the new dual-stack access portal URL when using IPv6 connectivity. Alternately, if your workforce accesses the application URL, you need to enable the dual-stack application URL following application-specific instructions. For more information, see AWS services that support IPv6.
The URLs that administrators use to manage IAM Identity Center are the second kind of URL your organization needs. The new dual-stack service endpoints end in api.aws as their TLD and are listed in the Identity Center service endpoints. Administrators can use these service endpoints to manage users and groups in Identity Center, update their access to applications and resources, and perform other management operations. As an example, if your administrator uses identitystore.{region}.amazonaws.com to manage users and groups in Identity Center, they should now use the dual-stack version of the same service endpoint which is identitystore.{region}.api.aws, so they can connect to service endpoints using IPv6 clients and networks.
If your users or administrators use an AWS SDK to access AWS applications and accounts or manage services, follow Dual-stack and FIPS endpoints to enable connectivity to the dual-stack endpoints.
After completing these two steps, your workforce and administrators can connect to IAM Identity Center using IPv6. Remember, these endpoints also support IPv4, so clients not yet IPv6-capable can continue to connect using IPv4.
Monitoring dual-stack endpoint usage
You can optionally monitor AWS CloudTrail logs to track usage of dual-stack endpoints. The key difference between IPv4-only and dual-stack endpoint usage is the TLD and appears in the clientProvidedHostHeader field. The following example shows the difference between these CloudTrail events for the CreateTokenWithIAM API call.
IAM Identity Center now allows clients to connect over IPv6 natively with no network address translation infrastructure. This post showed you how to transition your organization to use IPv6 with Identity Center and its integrated applications. Remember that existing IPv4 endpoints will continue to function, so you can transition at your own pace. Also, no immediate action is required by you. However, we recommend planning your transition to take advantage of IPv6 benefits and meet compliance requirements. If you have questions, comments, or concerns, contact AWS Support, or start a new thread in the IAM Identity Center re:Post channel.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Customers often want to deploy Amazon OpenSearch Service domains in virtual private clouds (VPC) and use single sign-on (SSO) with SAML for access control to enhance security. However, setting this up can be challenging.
In this post, we explore different OpenSearch Service authentication methods and network topology considerations. Then we show how to build an architecture to access an OpenSearch Service domain hosted in a VPC using AWS Client VPN, AWS Transit Gateway, and AWS IAM Identity Center.
Solution overview
The following diagram illustrates the solution architecture.
The end-user authenticates with IAM Identity Center and connects to the AWS environment from their browser through Client VPN. The traffic is routed from the VPN VPC to the database VPC where the OpenSearch service endpoints are deployed. The user then authenticates to OpenSearch Service through IAM Identity Center. This architecture provides a scalable, enterprise-grade solution that avoids using bastion hosts while making sure only authorized users can access your OpenSearch Service domains through a secure VPN connection. In the following sections, we walk through the steps to set up IAM Identity Center, configure Transit Gateway to facilitate communication between VPCs, and configure SAML-based authentication using IAM Identity Center for both OpenSearch Service and VPN access. Prior experience setting up Client VPN, IAM Identity Center, and Transit Gateway would be beneficial but is not necessary to follow along with this post.
OpenSearch Service authentication methods and SAML
OpenSearch Service supports multiple authentication methods. You can use AWS Identity and Access Management (IAM) to call the OpenSearch Service configuration API (for details, see Making and signing OpenSearch Service requests). However, this doesn’t give you access to the visual dashboard. To access the visual dashboard and call the OpenSearch Service configuration API, you can use the OpenSearch Service built-in internal user database or Amazon Cognito for authentication and user management features. However, these options use separate user pools, which adds additional security and management overhead when adding and removing users.
Therefore, many customers choose to use SAML federation to integrate OpenSearch Service authentication with their existing identity providers like Entra ID, Okta, or JumpCloud. For this post, we use the IAM Identity Center directory as our identity source. One limitation of this approach is that it only supports identity provider-initiated authentication. This means that users must log in through the IAM Identity Center portal and then access their OpenSearch Service dashboard from there.
Private network topology options for OpenSearch Service
When deploying OpenSearch Service domains in a private VPC, organizations must establish secure and reliable network connectivity to access their OpenSearch Service domains. AWS offers several networking solutions that can be implemented individually or in combination to meet specific access requirements. These options include Transit Gateway for centralized network management, AWS Direct Connect or AWS Site-to-Site VPN for on-premises connectivity, and Client VPN for secure remote access. Each solution provides unique benefits and can be combined to meet different organizational needs, security requirements, and performance expectations.
AWS Transit Gateway
Transit Gateway functions as a cloud router that simplifies network connectivity by acting as a central hub for connecting VPCs and on-premises networks. Implementing Transit Gateway with OpenSearch Service enables consolidated access to your OpenSearch Service domain across multiple VPCs and AWS accounts. Through Transit Gateway route tables, you can precisely control traffic flow between attached networks. It supports transitive routing between VPCs and on-premises networks, significantly reducing the number of peering connections needed to access your OpenSearch Service domain. This centralized approach is a common pattern used by customers, which makes network management scalable as your infrastructure grows.
AWS Client VPN
With Client VPN, you can securely access your private OpenSearch Service domain through a managed OpenVPN-based solution. Using Client VPN removes the need to use a bastion host or proxy server to access an OpenSearch Service domain, reducing your management burden and improving security. Client VPN supports both certificate-based and SAML-based authentication. Client VPN endpoints can be associated with multiple subnets to provide high availability. The service includes comprehensive security features such as connection logging and security group controls.
Combining Client VPN with Transit Gateway provides a scalable and flexible way to access an OpenSearch Service domain in a private VPC. In the subsequent sections, we walk you through how to integrate the various services.
Prerequisites
If you haven’t yet set up IAM Identity Center, refer to Enable IAM Identity Center to enable it. Both organization instances and account instances will work. The Identity Center instance must be deployed in the same AWS Region as your OpenSearch Service domain.
After you set up IAM Identity Center, complete the following steps to create an IAM Identity Center group:
On the IAM Identity Center console, choose Groups in the navigation pane.
Choose Create group and create a group (for this example, we name the group vpn_users.
After you create the group, choose the group name to open its details page.
Locate the group ID under General information. Save this in a text editor.
Create a user (or multiple users) and assign them to the vpn_users group. This can be done directly through the user creation flow or after creating the user.
Set up the initial network topology
For this post, we use the network topology shown in the following diagram. One VPC hosts the client VPN endpoint with CIDR range 10.0.0.0/16 and a separate VPC with CIDR range 10.1.0.0/16 that hosts our OpenSearch Service nodes. The two VPCs are connected with Transit Gateway. The CIDR ranges in your environment may vary. The only requirement is that they can’t overlap.
Next, you must update each VPC route table to facilitate connectivity to the OpenSearch Service domain.
On the Amazon VPC console, choose Route tables in the navigation pane.
For VPN-VPC, add routes on the subnets where the Client VPN endpoints are attached. The route is 10.1.0.0/16 using Transit Gateway. This route allows VPN users to reach Database-VPC.
For Database-VPC, add routes on the subnets of the OpenSearch Service domain endpoint. The route is 10.0.0.0/16 using Transit Gateway. This route allows responses from Database-VPC back to reach the VPN users.
Next, you must update the Transit Gateway Security Group Referencing support configuration. This allows the OpenSearch Service domain’s security group to open port 443 to only the Client VPN security group. This makes applying least privilege simpler.
On the Transit Gateway console, select the transit gateway you’re using.
On the Actions menu, choose Modify transit gateway.
Select Security Group Referencing support and choose Modify transit gateway.
Configure Client VPN authentication
Client VPN can be associated to multiple VPC subnets for high availability. Client VPN supports multiple client authentication methods. For this post, we use SAML-based authentication with IAM Identity Center.
To set up SAML-based authentication with IAM Identity Center, follow the instructions in the following sections. For more details, refer to Authenticate AWS Client VPN users with AWS IAM Identity Center. Deploy and associate the Client VPN endpoint with VPN-VPC.
Configure Client VPN access to database VPC
During the initial setup of the Client VPN endpoint, you defined authorization rules that authorized the VPN_users group to access the VPN-VPC network, which is 10.0.0.0/16.Complete the following steps to add connectivity to database-VPC:
On the Amazon VPC console, choose Client VPC endpoints in the navigation pane.
Select the endpoint you created.
In the Authorization rules section, choose Add authorization rules.
For Destination network to enable access, enter 10.1.0.0/16 (this is the database VPC).
For Grant access to, select Allow access to all users.
Choose Add authorization rule.
After you create the authorization rule, the user now has access to that CIDR range. Next, you add an entry in the Client VPN endpoint’s route table to provide reachability from a network perspective.
On the Client VPN endpoints page, select the endpoint you just created.
In the Route table section, choose Create route.
For Route destination, enter the CIDR range for Database-VPC (10.1.0.0/16).
For Subnet ID for target network association, choose a subnet ID.
Choose Create route.
You should see the new route in the “Creating” state. After it has reached the “Active” state, VPN users will have a network path to the database VPC to be able to reach the OpenSearch Service domain.
Configure Client VPN application on your client
Complete the following steps to configure the Client VPN application to your client:
Download the relevant installer for Client VPN for Desktop and install Client VPN.
Download and prepare the Client VPN endpoint file.
Open the Client VPN application.
Choose Manage Profile, then choose Add Profile.
Enter a display name and upload the VPN configuration file.
Choose Add Profile.
Set up federation with IAM Identity Center with OpenSearch Service
Complete the following steps to set up federation with IAM Identity Center with OpenSearch Service:
Set up the SAML integration between OpenSearch Service and IAM Identity Center. Assign the same groups that you assigned to the VPN custom application to the OpenSearch Service custom application.
Modify the security group associated with the OpenSearch Service domain to allow access from the Client VPN subnet.
Modify the security group of Client VPN and add the following entry:
Type: HTTPS
Source: Use Custom and reference the security group of the OpenSearch Service domain
Test the end-to-end flow
Now you can test the entire flow end-to-end:
Run Client VPN on your local machine. Use the profile that you previously configured. The client will prompt you to authenticate with IAM Identity Center. After authentication, you will see the message “Authentication details received, processing details. You may close this window at any time.”
Access your IAM Identity Center access portal URL (this can be found on the IAM Identity Center console, under Dashboard). Sign in as a user that has been assigned to the OpenSearch Service custom application in the previous step.
After authentication, choose the Applications tab in AWS Access Portal and choose the OpenSearch Service application.
This should redirect you to the OpenSearch Service Dashboards page with the role that you assigned.
Clean up
After you test the solution, delete the resources you created to avoid incurring future charges:
Delete the OpenSearch Service domain and the SAML application, users, and groups in IAM Identity Center.
Delete the client VPN endpoints that you created and remove the routing rules from Transit Gateway.
Conclusion
In this post, we discussed the networking options for securely accessing an OpenSearch Service domain deployed in a private VPC through services like Transit Gateway, Client VPN, and Site-to-Site VPN. We also discussed how to use IAM Identity Center for authentication and authorization, helping you simplify identity management for OpenSearch Service. If you have feedback about this post, provide it in the comments section.
Many organizations are using an external identity provider to manage user identities. With an identity provider (IdP), you can manage your user identities outside of AWS and give these external user identities permissions to use AWS resources in your AWS accounts. External identity providers (IdP), such as Okta Universal Directory, can integrate with AWS IAM Identity Center to be the source of truth for Amazon SageMaker Unified Studio.
Amazon SageMaker Unified Studio supports a single sign-on (SSO) experience with AWS IAM Identity Center authentication. Users can access Amazon SageMaker Unified Studio with their existing corporate credentials. AWS IAM Identity Center enables administrators to connect their existing external identity providers and allows them to manage users and groups in their existing identity systems such as Okta which can then be synchronized with AWS IAM Identity Center using SCIM (System for Cross-domain Identity Management).
This post shows step-by-step guidance to setup workforce access to Amazon SageMaker Unified Studio using Okta as an external Identity provider with AWS IAM Identity Center.
Prerequisites
Before you start , make sure you have:
An AWS account with AWS IAM Identity Center enabled . It is recommended to use an organization-level AWS IAM Identity Center instance for best practices and centralized identity management across your AWS organization.
Okta account with users and a group
A browser with network connectivity to Okta and Amazon SageMaker Unified Studio
Solution Overview
The steps in this post are structured into the following sections:
Enable AWS IAM Identity Center
Create an Amazon SageMaker domain
Setup Okta users and groups
Configure SAML in Okta for AWS IAM Identity Center
Configure Okta as an identity provider in AWS IAM Identity Center
Connect AWS IAM Identity Center to Okta
Set up automatic provisioning of users and groups in AWS IAM Identity Center
Complete Okta Configuration
Configure Amazon SageMaker Unified Studio for SSO
Test the setup
Cleanup
Enable AWS IAM Identity Center
To enable AWS IAM Identity Center, follow the instructions in Enable IAM Identity Center in the AWS IAM Identity Center User Guide.
Choose Directory in the left menu and choose Groups to proceed.
Click on Add Group and enter name as unifiedstudio. Then choose the Save button.
Figure 2. Creating a group in Okta
Step 3: Create users in Okta
Choose People in left menu under Directory section and choose +Add Person.
Provide First name, Last name, username (email ID), and primary email. Then select I will set password and choose first time password. Use the Save button to create your user.
Add more users as needed.
Step 4: Assign Groups to users
Choose Groups from the left menu, then choose the unifiedstudiogroup created in Step 2.
Use Assign People to add users to the sagemaker group. Next, use + for each user you want to add.
Configure SAML In Okta
Login to your okta domain and choose Applications from the left menu. Choose Applications, then choose Browse App Catalog
In the search box, enter AWS IAM Identity Center, then choose the app to add the AWSIAM Identity Center app and then, choose + Add Integration button. The following image shows the SAML app integration setup: Figure 3. Creating a SAML app integration in Okta
For this example, we are creating an application called “unifiedstudio”. Under General Settings:Required enter the following
Application label = Replace IAM Identity Center with unifiedstudio and then, choose Save
Under Sign on menu. Copy Metadata URL under SAML 2.0 section and then, open Metadata URL in a new browser window to download the Okta identity provider metadata and save it as metadata.xml. You will use this for the SAML configuration in AWS IAM Identity Center to setup Okta as an Identity Provider.The following image shows where to find the metadata URL:
Figure 4: Downloading Okta identity provider metadata for SAML configuration
Choose More details and copy Sign on URL into text file; you will use this for the SAML configuration in Amazon SageMaker Unified Studio.
You are now ready to move to the AWS IAM Identity Center console to create an identity provider integration for your Okta instance.
Configure Okta as an identity provider in AWS IAM Identity Center
In the left navigation menu, choose Settings and then, open the Identity source tab, choose Change Identity source from Actions dropdown as shown in Figure 5 Figure 5: Selecting identity source in AWS IAM Identity Center
From Under Identity source, choose External Identity provider as shown in Figure 6 Figure 6: Choosing External Identity provider in AWS IAM Identity Center
You’ll need these configuration parameters for the next step. In Configure external identity provider section, under Service Provider metadata, do the following:
Choose Download metadata file to download the AWS IAM Identity Center metadata file and save it on your system
Copy these Service Provider metadata into a text file
IAM Identity Center Assertion Consumer Service (ACS) URL
IAM Identity Center issuer URL
In Identity provider metadata section, under Idp SAML metadata, click on choose file and upload the metadata.xml file which you downloaded from okta in the previous step and then, choose Next as shown in Figure 7
Figure 7. Configuring okta as Identity Provider in AWS IAM Identity Center
After you read the disclaimer and are ready to proceed, enter ACCEPT and then choose Change identity source to complete Okta as an Identity Provider in IAM Identity Center.
Connect AWS IAM Identity Center to Okta
Sign into Okta and go to the admin console.
In the left navigation pane, choose Applications, and then choose the Okta application called unifiedstudio which you created in the previous section
In Sign On, choose Edit to complete SAML configuration. Under Advanced Sign-on Settings enter the following and then, choose Save to complete configuration as shown Figure 8.
For the AWS SSO ACS URL, enter IAM Identity Center Assertion Consumer Service (ACS) URL
For the AWS SSO issuer URL, enter IAM Identity Center issuer URL
For the Application username format, choose Okta username from dropdown
Figure 8. Configuring okta sign-on settings
Set up automatic provisioning of users and groups
In the AWS IAM Identity Center console, on the Settings page, locate the Automatic provisioning information box, and then choose Enable as shown in Figure 9. Copy these values to enable automatic provisioning.
Figure 9. Enabling automatic provisioning in AWS IAM Identity Center
In the Inbound automatic provisioning dialog box, copy each of the values for the following options as shown in Figure 10 and then, choose Close
SCIM endpoint
Access token
You will use these values to configure provisioning in Okta in the next step.
Figure 10. Automatic provisioning configuration parameters in AWS IAM Identity Center
Complete the Okta integration
Sign into Okta and go to the admin console.
In the left navigation pane, choose Applications, and then choose the Okta application called unifiedstudio which you created earlier.
In Provisioning tab, choose Edit to complete auto provisioning between okta and AWS IAM Identity Center.
Under Settings, choose Integration and then, choose Configure API integration and then, select Enable API integration to enable provisioning and enter the following using the SCIM provisioning values from AWS IAM Identity Center that you copied from the previous step as shown in Figure 11
For the Base URL, enter SCIM endpoint from IAM Identity Center For the API Token, enter Access token from IAM Identity Center For Import Groups, select Import groups option
And then, choose Test API Credentials to validate the SCIM provision and then, choose Save.
Figure 11: Automatic provisioning configuration in Okta
In the Provisioning tab, in the navigation pane under Settings, choose To App in the left navigation. Choose Edit, to Enable all options such as Create Users , Update User Attributes , Deactivate Users as shown in Figure 12 and then, choose Save.
Figure 12: Enabling Automatic provisioning configuration in Okta
In the Assignments tab, choose Assign, and then Assign to Groups.
Select the unifiedstudio group, choose Assign, and then, leave it to defaults on popup and then, choose Done to complete the Group assignment, as shown in Figure 13.
Figure 13: Assigning unifiedstudio group to SAML application called unifiedstudio
In the Push Groups tab, under Push Groups drop-down list, select Find groups by name as shown in Figure 14.
Figure 14: Choosing okta groups to push them to AWS IAM Identity Center
Select the unifiedstudio group, leave Push group memberships immediately default option and then, choose Save as shown in Figure 15.
Figure 15: Pushing okta groups to AWS IAM Identity Center
Return to AWS IAM Identity Center, and you should be able to see Okta group and Okta users in AWS IAM Identity Center groups and users as shown In Figure 16.
Figure 16: Okta user groups in AWS IAM Identity Center
Configure SageMaker Unified Studio for SSO
In this step, you will configure SSO user access to Amazon SageMaker Unified Studio for your Amazon SageMaker platform domain.
Navigate to the Amazon SageMaker management console.
In the left navigation menu, select Domains.
Choose the Domain from the list for which you want to configure SAML user access.
On the domain’s details page, choose Configure next to the Configure SSO user access. Figure 17: Amazon SageMaker Unified Studio SSO configuration
On the Choose user authentication method page, choose IAM Identity Center. With IAM Identity Center, users configured through external Identity Providers (IdPs) get to access the domain’s Amazon SageMaker Unified Studio. Choose Next. Figure 18: Choosing authentication
You can choose either Require assignments – which means you explicitly select users/groups that can access the domain or Do not require assignments – which allows all authorized Okta users and groups access to this domain.
You have two options to configure how your users will access to Amazon SageMaker Unified studio with AWS IAM Identity Center federation with Okta
Do not required Assignments – The access will be provided to Amazon SageMaker Unified Studio based on your Okta SAML application assignments either through Group assignments or Individual user assignments. For this example, when you choose Do not required assignments option, all the users within unifiedstudio Okta group will have access to Amazon SageMaker Unified Studio as we have assigned unifiedstudio Okta user group to unifiedstudio SAML application in Okta.
Require Assignments – You need to add either Okta users or Okta group to Amazon SageMaker domain as shown in step 8. In step 8, you’ll add unifiedstudio Okta group into Amazon SageMaker domain so that all unifiedstudio Okta group users will get access to Amazon SageMaker Unified Studio. You can also provide an Individual Okta group users access to Amazon SageMaker unified studio through Amazon SageMaker domain console by adding SSO (okta user) user into the domain.
Note that either an Individual user or group within Okta must be assigned to the AWS Identity center application (AWS IAM Identity Center from Okta application catalog. We renamed application label as unifiedstudio for this example) for both Do not require Assignments and Require Assignments options.
Figure 19. Amazon SageMaker Unified Studio SAML configuration
On the Review and save page, review your choices and then choose Save. Note that these settings are permanent once saved.
Figure 20. Review and confirm SAML configuration
If you’ve chosen to require assignments, use the Add users and groups to add SAML users and groups to your domain.
Figure 21. Adding okta group into Amazon Sagemaker domain
Now, users will be able to access the Amazon SageMaker Unified Studio using the Domain URL with their SSO credentials.
You can explore different projects for your users and assign those projects based on your SAML user groups for fine-grained access controls. For example, you can create different SAML user groups based on their job function in Okta, assign those Okta groups to AWS IAM Identity Center app in Okta and then, assign those Okta SAML groups to respective project profiles in Amazon SageMaker Unified Studio. To perform project profiles assignments to respective groups, choose project profiles tab, click on respective project profiles like SQL analytics, choose Authorized users and groups tab and then, choose Add and pick SSO groups from drop down as shown in Figure 22. Finally choose Add users and groups to complete project profile assignment.
Figure 22. Assigning a project profile to okta group
Test the setup
The Amazon SageMaker Unified Studio URL can be found on the domain details page as shown in Figure 23. The first access to Amazon SageMaker Unified Studio URL redirects you to the Okta login screen.
Figure 23. Validating Okta user access with Amazon SageMaker Unified Studio
Copy and paste the Amazon SageMaker Unified Studio URL in your browser and enter the user credentials.
After successful login, you will be redirected to the Amazon SageMaker Unified Studio home page.
Figure 24. SAML authenticated Amazon SageMaker Unified Studio
Once logged into Amazon SageMaker Unified Studio, you can assign authorization policies based on your requirements. Choose Govern and then choose, Domain units and choose your SageMaker domain to select suitable authorization policies. For this example, we are choosing project creation policy as shown in Figure 25.
Figure 25. Amazon SageMaker unified studio authorization policies
Choose Project membership policy and then choose ADD POLICY GRANT option to assign user groups or users to respective project. For this example, we are choosing project membership policy as shown in Figure 26.
Figure 26. Amazon SageMaker unified studio authorization policies assignment
You’ve now successfully configured single sign-on for Amazon SageMaker Unified Studio using Okta credentials through AWS IAM Identity Center.
Clean up
To avoid ongoing charges, delete the resources you created:
In this post, we showed you how to set up Okta as an identity provider using SAML authentication for Amazon SageMaker Unified Studio access through AWS IAM Identity Center federation. This setup allows your users to access SageMaker Unified Studio with their existing corporate credentials, eliminating the need for separate AWS accounts.
Many organizations operating in regulated industries need complete control over encryption key management. While Identity Center already encrypts data at rest using AWS-owned keys, some customers require the ability to manage their own encryption keys for audit and compliance purposes.
With this launch, you can now use customer-managed KMS keys (CMKs) to encrypt Identity Center identity data at rest. CMKs provide you with full control over the key lifecycle, including creation, rotation, and deletion. You can configure granular access controls to keys with AWS Key Management Service (AWS KMS) key policies and IAM policies, helping to ensure that only authorized principals can access your encrypted data. At launch time, the CMK must reside in the same AWS account and Region as your IAM Identity Center instance. The integration between Identity Center and KMS provides detailed AWS CloudTrail logs for auditing key usage and helps meet regulatory compliance requirements.
Identity Center supports both single-Region and multi-Region keys to match your deployment needs. While Identity Center instances can currently only be deployed in a single Region, we recommend using multi-Region AWS KMS keys unless your company policies restrict you to single-Region keys. Multi-Region keys provide consistent key material across Regions while maintaining independent key infrastructure in each Region. This gives you more flexibility in your encryption strategy and helps future-proof your deployment.
Let’s get started Let’s imagine I want to use a CMK to encrypt the identity data of my Identity Center organization instance. My organization uses Identity Center to give employees access to AWS managed applications, such as Amazon Q Business or Amazon Athena.
As of today, some AWS managed applications cannot be used with Identity Center configured with a customer managed KMS key. See AWS managed applications that you can use with Identity Center to keep you updated with the ever evolving list of compatible applications.
The high-level process requires first to create a symmetric customer managed key (CMK) in AWS KMS. The key must be configured for encrypt and decrypt operations. Next, I configure the key policies to grant access to Identity Center, AWS managed applications, administrators, and other principals who need access the Identity Center and IAM Identity Center service APIs. Depending on your usage of Identity Center, you’ll have to define different policies for the key and IAM policies for IAM principals. The service documentation has more details to help you cover the most common use cases.
This demo is in three parts. I first create a customer managed key in AWS KMS and configure it with permissions that will authorize Identity Center and AWS managed applications to use it. Second, I update the IAM policies for the principals that will use the key from another AWS account, such as AWS applications administrators. Finally, I configure Identity Center to use the key.
Part 1: Create the key and define permissions
First, let’s create a new CMK in AWS KMS.
The key must be in the same AWS Region and AWS account as the Identity Center instance. You must create the Identity Center instance and the key in the management account of your organization within AWS Organization.
I navigate to the AWS Key Management Service (AWS KMS) console in the same Region as my Identity Center instance, then I choose Create a key. This launches me into the key creation wizard.
Under Step 1–Configure key, I select the key type–either Symmetric (a single key used for both encryption and decryption) or Asymmetric (a public-private key pair for encryption/decryption and signing/verification). Identity Center requires symmetric keys for encryption at rest. I select Symmetric.
For key usage, I select Encrypt and decrypt which allows the key to be used only for encrypting and decrypting data.
Under Advanced options, I select KMS – recommended for Key material origin, so AWS KMS creates and manages the key material.
For Regionality, I choose between Single-Region or Multi-Region key. I select Multi-Region key to allow key administrators to replicate the key to other Regions. As explained already, Identity Center doesn’t require this today but it helps to future-proof your configuration. Remember that you can not transform a single-Region key to a multi-Region one after its creation (but you can change the key used by Identity Center).
Then, I choose Next to proceed with additional configuration steps, such as adding labels, defining administrative permissions, setting usage permissions, and reviewing the final configuration before creating the key.
Under Step 2–Add Labels, I enter an Alias name for my key and select Next.
In this demo, I am editing the key policy by adding policy statements using templates provided in the documentation. I skip Step 3 and Step 4 and navigate to Step 5–Edit key policy.
Identity Center requires, at the minimum, permissions allowing Identity Center and its administrators to use the key. Therefore, I add three policy statements, the first and second authorize the administrators of the service, the third one to authorize the Identity Center service itself.
I also have to add additional policy statements to allow my use case: the use of AWS managed applications. I add these two policy statements to authorize AWS managed applications and their administrators to use the KMS key. The document lists additional use cases and their respective policies.
To help protect against IAM role name changes when permission sets are recreated, use the approach described in the Custom trust policy example.
Part 2: Update IAM policies to allow use of the KMS key from another AWS account
Any IAM principal that uses the Identity Center service APIs from another AWS account, such as Identity Center delegated administrators and AWS application administrators, need an IAM policy statement that allows use of the KMS key via these APIs.
I grant permissions to access the key by creating a new policy and attaching the policy to the IAM role relevant for my use case. You can also add these statements to the existing identity-based policies of the IAM role.
Part 3: Configure IAM Identity Center to use the key
I can configure a CMK either during the enablement of an Identity Center organization instance or on an existing instance, and I can change the encryption configuration at any time by switching between CMKs or reverting to AWS-owned keys.
Please note that an incorrect configuration of KMS key permissions can disrupt Identity Center operations and access to AWS managed applications and accounts through Identity Center. Proceed carefully to this final step and ensure you have read and understood the documentation.
After I have created and configured my CMK, I can select it under Advanced configuration when enabling Identity Center.
To configure a CMK on an existing Identity Center instance using the AWS Management Console, I start by navigating to the Identity Center section of the AWS Management Console. From there, I select Settings from the navigation pane, then I select the Management tab, and select Manage encryption in the Key for encrypting IAM Identity Center data at rest section.
At any time, I can select another CMK from the same AWS Account, or switch back to an AWS-managed key.
After choosing Save, the key change process takes a few seconds to complete. All service functionalities continue uninterrupted during the transition. If, for whatever reasons, Identity Center can not access the new key, an error message will be returned and Identity Center will continue to use the current key, keeping your identity data encrypted with the mechanism it is already encrypted with.
Things to keep in mind The encryption key you create becomes a crucial component of your Identity Center. When you choose to use your own managed key to encrypt identity attributes at rest, you have to verify the following points.
Have you configured the necessary permissions to use the KMS key? Without proper permissions, enabling the CMK may fail or disrupt IAM Identity Center administration and AWS managed applications.
Have you verified that your AWS managed applications are compatible with CMK keys? For a list of compatible applications, see AWS managed applications that you can use with IAM Identity Center. Enabling CMK for Identity Center that is used by AWS managed applications incompatible with CMK will result in operational disruption for those applications. If you have incompatible applications, do not proceed.
Is your organization using AWS managed applications that require additional IAM role configuration to use the Identity Center and Identity Store APIs? For each such AWS managed application that’s already deployed, check the managed application’s User Guide for updated KMS key permissions for IAM Identity Centre usage and update them as instructed to prevent application disruption.
Pricing and availability Standard AWS KMS charges apply for key storage and API usage. Identity Center remains available at no additional cost.
This capability is now available in all AWS commercial Regions, AWS GovCloud (US), and AWS China Regions. To learn more, visit the IAM Identity Center User Guide.
We look forward to learning how you use this new capability to meet your security and compliance requirements.
Amazon Redshift is a powerful cloud-based data warehouse that organizations can use to analyze both structured and semi-structured data through advanced SQL queries. As a fully managed service, it provides high performance and scalability while allowing secure access to the data stored in the data warehouse. Organizations worldwide rely on Amazon Redshift to handle massive datasets, upgrade their analytics capabilities, and deliver valuable business intelligence to their stakeholders.
AWS IAM Identity Center serves as the preferred platform for controlling workforce access to AWS tools, including Amazon Q Developer. It allows for a single connection to your existing identity provider (IdP), creating a unified view of users across AWS applications and applying trusted identity propagation for a smooth and consistent experience.
You can access data in Amazon Redshift using local users or external users. A local user in Amazon Redshift is a database user account that is created and managed directly within the Redshift cluster itself. Amazon Redshift also integrates with IAM Identity Center, and supports trusted identity propagation, so you can use third-party IdPs such as Microsoft Entra ID (Azure AD), Okta, Ping, OneLogin, or use IAM Identity Center as an identity source. The IAM Identity Center integration with Amazon Redshift supports centralized authentication and SSO capabilities, simplifying access management across multi-account environments. As organizations grow in scale, it is recommended to use external users for cross-service integration and centralized access management.
In this post, we walk you through the process of smoothly migrating your local Redshift user management to IAM Identity Center users and groups using the RedshiftIDCMigration utility.
Solution overview
The following diagram illustrates the solution architecture.
The RedshiftIDCMigration utility accelerates the migration of your local Redshift users, groups, and roles to your IAM Identity Center instance by performing the following activities:
Create users in IAM Identity Center for every local user in a given Redshift instance.
Create groups in IAM Identity Center for every group or role in a given Redshift instance.
Assign users to groups in IAM Identity Center according to existing assignments in the Redshift instance.
Create IAM Identity Center roles in the Redshift instance matching the groups created in IAM Identity Center.
Grant permissions to IAM Identity Center roles in the Redshift instance based on the current permissions given to local groups and roles.
Prerequisites
Before running the utility, complete the following prerequisites:
Configure the IAM Identity Center application assignments:
On the IAM Identity Center console, choose Application Assignments and Applications.
Select your application and on the Actions dropdown menu, choose Edit details.
For User and group assignments, choose Do not require assignments. This setting makes it possible to test Amazon Redshift connectivity without configuring specific data access permissions.
The utility will be run from either an EC2 instance or CloudShell. If you’re using an EC2 instance, an IAM role is attached to the instance. Make sure that the IAM role used during the execution has the following permissions (if not, create a new policy with those permissions and attach it to the IAM role):
Download the following utility artifacts from the GitHub repo:
idc_redshift_unload_indatabase_groups_roles_users.py – A Python script to unload users, groups, roles and their associations.
redshift_unload.ini – The config file used in the preceding script to read Redshift data warehouse details and Amazon S3 locations to unload the files.
idc_add_users_groups_roles_psets.py – A Python script to create users and groups in IAM Identity Center, and then associate the users to groups in IAM Identity Center.
idc_config.ini – The config file used in the preceding script to read IAM Identity Center details.
vw_local_ugr_to_idc_urgr_priv.sql – A script that generates SQL statements that perform two tasks in Amazon Redshift:
Create roles that exactly match your IAM Identity Center group names, adding a specified prefix.
Grant appropriate permissions to these newly created Redshift roles.
Testing scenario
This test case is designed to offer practical experience and familiarize you with the utility’s functionality. The scenario is structured around a hierarchical nested roles system, starting with object-level permissions assigned to technical roles. These technical roles are then allocated to business roles. Finally, business roles are granted to individual users. To enhance the testing environment, the scenario also incorporates a user group.The following diagram illustrates this hierarchy.
Create datasets
Set up two separate schemas (tickit and tpcds) in a Redshift database using the create schema command. Then, create and populate a few tables in each schema using the tickit and tpcds sample datasets.
Specify the appropriate IAM role Amazon Resource Name (ARN) in the copy commands if necessary.
Create users
Create users with the following code:
-- ETL users
create user etl_user_1 password 'EtlUser1!';
create user etl_user_2 password 'EtlUser2!';
create user etl_user_3 password 'EtlUser3!';

-- Reporting users
create user reporting_user_1 password 'ReportingUser1!';
create user reporting_user_2 password 'ReportingUser2!';
create user reporting_user_3 password 'ReportingUser3!';

-- Adhoc users
create user adhoc_user_1 password 'AdhocUser1!';
create user adhoc_user_2 password 'AdhocUser2!';

-- Analyst users
create user analyst_user_1 password 'AnalystUser1!';
Create business roles
Create business users with the following code:
-- ETL business roles
create role role_bn_etl_tickit;
create role role_bn_etl_tpcds;

-- Reporting business roles
create role role_bn_reporting_tickit;
create role role_bn_reporting_tpcds;

-- Analyst business roles
create role role_bn_analyst_tickit;
Create technical roles
Create technical roles with the following code:
-- Technical roles for tickit schema
create role role_tn_sel_tickit;
create role role_tn_dml_tickit;
create role role_tn_cte_tickit;

-- Technical roles for tpcds schema
create role role_tn_sel_tpcds;
create role role_tn_dml_tpcds;
create role role_tn_cte_tpcds;
Create groups
Create groups with the following code:
-- Adhoc users group
create group group_adhoc;
Grant rights to technical roles
To grant rights to the technical roles, use the following code:
-- role_tn_sel_tickit
grant usage on schema tickit to role role_tn_sel_tickit;
grant select on all tables in schema tickit to role role_tn_sel_tickit;

-- role_tn_dml_tickit
grant usage on schema tickit to role role_tn_dml_tickit;
grant insert, update, delete on all tables in schema tickit to role role_tn_dml_tickit;

-- role_tn_cte_tickit
grant usage, create on schema tickit to role role_tn_cte_tickit;
grant drop on all tables in schema tickit to role role_tn_cte_tickit;

-- role_tn_sel_tpcds
grant usage on schema tpcds to role role_tn_sel_tpcds;
grant select on all tables in schema tpcds to role role_tn_sel_tpcds;

-- role_tn_dml_tpcds
grant usage on schema tpcds to role role_tn_dml_tpcds;
grant insert, update, delete on all tables in schema tpcds to role role_tn_dml_tpcds;

-- role_tn_cte_tpcds
grant usage, create on schema tpcds to role role_tn_cte_tpcds;
grant drop on all tables in schema tpcds to role role_tn_cte_tpcds;
Grant technical roles to business roles
To grant the technical roles to the business roles, use the following code:
-- Business role role_bn_etl_tickit
grant role role_tn_sel_tickit to role role_bn_etl_tickit;
grant role role_tn_dml_tickit to role role_bn_etl_tickit;
grant role role_tn_cte_tickit to role role_bn_etl_tickit;

-- Business role role_bn_etl_tpcds
grant role role_tn_sel_tpcds to role role_bn_etl_tpcds;
grant role role_tn_dml_tpcds to role role_bn_etl_tpcds;
grant role role_tn_cte_tpcds to role role_bn_etl_tpcds;

-- Business role role_bn_reporting_tickit
grant role role_tn_sel_tickit to role role_bn_reporting_tickit;

-- Business role role_bn_reporting_tpcds
grant role role_tn_sel_tpcds to role role_bn_reporting_tpcds;

-- Business role role_bn_analyst_tickit
grant role role_tn_sel_tickit to role role_bn_analyst_tickit;
Grant business roles to users
To grant the business roles to users, use the following code:
-- etl_user_1
grant role role_bn_etl_tickit to etl_user_1;

-- etl_user_2
grant role role_bn_etl_tpcds to etl_user_2;

-- etl_user_3
grant role role_bn_etl_tickit to etl_user_3;
grant role role_bn_etl_tpcds to etl_user_3;

-- reporting_user_1
grant role role_bn_reporting_tickit to reporting_user_1;

-- reporting_user_2
grant role role_bn_reporting_tpcds to reporting_user_2;

-- reporting_user_3
grant role role_bn_reporting_tickit to reporting_user_3;
grant role role_bn_reporting_tpcds to reporting_user_3;

-- analyst_user_1
grant role role_bn_analyst_tickit to analyst_user_1;
Grant rights to groups
To grant rights to the groups, use the following code:
-- Group group_adhoc
grant usage on schema tickit to group group_adhoc;
grant select on all tables in schema tickit to group group_adhoc;

grant usage on schema tpcds to group group_adhoc;
grant select on all tables in schema tpcds to group group_adhoc;
Add users to groups
To add users to the groups, use the following code:
alter group group_adhoc add user adhoc_user_1;
alter group group_adhoc add user adhoc_user_2;
Deploy the solution
Complete the following steps to deploy the solution:
Update Redshift cluster or serverless endpoint details and Amazon S3 location in redshift_unload.ini:
cluster_type = provisioned or serverless
cluster_id = ${cluster_identifier} (required if cluster_type is provisioned)
db_user = ${database_user}
db_name = ${database_name}
host = ${host_url} (required if cluster_type is provisioned)
port = ${port_number}
workgroup_name = ${workgroup_name} (required if cluster_type is serverless)
region = ${region}
s3_bucket = ${S3_bucket_name}
roles = roles.csv
users = users.csv
role_memberships = role_memberships.csv
Update IAM Identity Center details in idc_config.ini:
region = ${region}
account_id = ${account_id}
identity_store_id = ${identity_store_id} (available on the IAM Identity Center console Settings page)
instance_arn = ${iam_identity_center_instance_arn} (available on the IAM Identity Center console Settings page)
permission_set_arn = ${permission_set_arn}
assign_permission_set = True or False (True if permission_set_arn is defined)
s3_bucket = ${S3_bucket_name}
users_file = users.csv
roles_file = roles.csv
role_memberships_file = role_memberships.csv
Create a directory in CloudShell or on your own EC2 instance with connectivity to Amazon Redshift.
Copy the two .ini files and download the Python scripts to that directory.
Run idc_redshift_unload_indatabase_groups_roles_users.py either from CloudShell or your EC2 instance:python idc_redshift_unload_indatabase_groups_roles_users.py
Run idc_add_users_groups_roles_psets.py either from CloudShell or your EC2 instance:python idc_add_users_groups_roles_psets.py
Connect your Redshift cluster using the Amazon Redshift query editor v2 or preferred SQL client, using superuser credentials.
Copy the SQL in the vw_local_ugr_to_idc_urgr_priv.sql file and run it in the query editor to create the vw_local_ugr_to_idc_urgr_priv view.
Run following SQL command to generate the SQL statements for creating roles and permissions:
select existing_grants,idc_based_grants from vw_local_ugr_to_idc_urgr_priv;
For example, consider the following existing grants:
CREATE GROUP "group_adhoc";
CREATE ROLE "role_bn_etl_tickit";
GRANT USAGE ON SCHEMA tpcds TO role "role_tn_sel_tpcds" ;
These grants are converted to the following code:
CREATE role "AWSIDC:group_adhoc";
CREATE role "AWSIDC:role_bn_etl_tickit";
GRANT USAGE ON SCHEMA tpcds TO role "AWSIDC:role_tn_sel_tpcds";
Review the statements in the idc_based_grants column. This might not be a comprehensive list of permissions, so review them carefully.
If everything is correct, run the statements from the SQL client.
When you have completed the process, you should have the following configuration:
IAM Identity Center now contains newly created users from Amazon Redshift
The Redshift local groups and roles are created as groups in IAM Identity Center
New roles are established in Amazon Redshift, corresponding to the groups created in IAM Identity Center
The newly created Redshift roles are assigned appropriate permissions
At the time of writing, creating permissions in AWS Lake Formation is not in scope.
IAM Identity Center and IdP integration setup is out of scope for this utility. However, you can use the view vw_local_ugr_to_idc_urgr_priv.sqlto create roles and grant permissions to the IdP users and groups passed through IAM Identity Center.
If you have permissions given directly to local user IDs (not using groups or roles), you must change that to a role-based permission approach for IAM Identity Center integration. Create roles and provide permissions using roles instead of directly giving permissions to users.
Clean up
If you have completed the testing scenario, clean up your environment:
Remove the new Redshift roles that were created by the utility, corresponding to the groups established in IAM Identity Center.
Delete the users and groups created by the utility within IAM Identity Center.
Delete the users, groups, and roles specified in the testing scenario.
Drop the tickit and tpcds schemas.
You can use the FORCE parameter when dropping the roles to remove associated assignments.
Conclusion
In this post, we showed how to migrate your Redshift local user management to IAM Identity Center. This transition offers several key advantages for your organization, such as simplified access management through centralized user and group administration, a streamlined user experience across AWS services, and reduced administrative overhead. You can implement this migration process step by step, so you can test and validate each step before fully transitioning your production environment.
As organizations continue to scale their AWS infrastructure, using IAM Identity Center becomes increasingly valuable for maintaining secure and efficient access management, including Amazon SageMaker Unified Studio for an integrated experience for all your data and AI.
As organizations scale their development efforts, AI coding assistants that understand organization-specific patterns and standards lead to more efficient development processes and higher quality software delivery. Amazon Q Developer Pro helps address this challenge by allowing organizations to customize the AI assistant with their proprietary code and development practices. Through Amazon Q Developer profiles, teams can efficiently manage access to Amazon Q customizations across different regions and AWS Identity Centers.
In this post, we will explore different approaches for implementing and managing Amazon Q Developer profiles and Amazon Q customizations across large organizations. Using an example with multiple business units, we will explore methods for managing access controls and customization governance while addressing security and compliance requirements.
Amazon Q customization is now available in both the US East (N. Virginia) and EU Central (Frankfurt) regions, giving teams more flexibility to create and deploy customizations closer to their operational hubs while meeting regional data residency requirements.
This blog is not intended to provide recommendations on how to structure your AWS accounts or divide Q Developer subscriptions. Rather, our aim is to explore the full capabilities of Q Developer Customizations in a comprehensive scenario that shows the current art of the possible.
A distributed Amazon Q Developer Pro subscriptions scenario
The following diagram illustrates a sample AWS Organizations structure with a Management Account and four Organizational Units (OUs). This is a common enterprise scenario with three business units, each business unit requiring their own Amazon Q Developer Pro subscription and customizations.
Figure 1: AWS Organizations Structure and Resource Hierarchy
The Infrastructure OU has a Delegated Admin Account with delegated access to the AWS IAM Identity Center. There are three additional OUs: Alpha, Bravo, and Charlie, each with at least one Amazon Q Developer Pro subscription. Alpha account has Amazon Q Developer subscriptions both in US East (N. Virginia) and EU Central (Frankfurt) region.
Think of each business unit as its own ecosystem within your organization. When you provide dedicated Q Developer Pro subscriptions to different OUs, you’re essentially giving each unit its own personalized AI assistant. This separation is valuable because it allows each team to work independently while maintaining their specific requirements and workflows.
The Charlie OU maintains its own account instance of IAM Identity Center for Amazon Q Developer Pro. In most cases, we recommend using an organization instance of IAM Identity Center with Amazon Q Developer Pro, there are a few situations where member account instances might make sense, for example: when you do not have a single identity provider, or when you haven’t yet decided to deploy it to the whole organization and want to use Amazon Q just for the AWS account you control.
Note: When a developer has a user within an Amazon Q profile tied to two different IAM Identity Center instances (Bravo and Charlie), they will have two user subscriptions and be billed twice. However, if they belong to two different Amazon Q profiles in two different accounts (Alpha and Bravo) but under the same IAM Identity Center, they will only be billed once.
In our example, the Charlie OU requires additional operational overhead in managing separate credentials and authentication flows. Additionally, the dashboard and administrative settings will only be associated with users and groups within this account. From an administrative perspective, instead of trying to manage one centralized configuration that attempts to serve everyone’s needs, you can distribute administration to each business unit and delegate responsibility to individual teams.
It’s like having different specialized departments in a hospital – while they’re all part of the same organization and can work together when needed, each department has its own specialized tools and protocols that help them perform their specific functions more effectively.
A strategic approach to Customizations through Q Developer profiles
Figure 2 Developers association to Amazon Q Developer Pro Subscriptions, Customizations and IAM Identity Centers
Amazon Q Developer profiles are the way developers connect to different Amazon Q Developer subscriptions through their IDE. Each profile represents a unique combination of an Amazon Q Developer subscription and its associated customizations. After authentication, developers can simply select or switch between profiles in their IDE to access different customizations.
Let’s walk through some scenarios in this architecture.
Scenario 1 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account
Developers from the Orange team with access to Alpha account customizations can configure two different Amazon Q Developer profiles in their IDE:
A “US Profile” connected to the US East subscription in the Alpha account
An “EU Profile” connected to the EU Central subscription in the Alpha account
Switching between different sets of customizations involves selecting the relevant profile within their IDE.
Figure 3 IDE showing customizations available for Team Orange developers switching between US and EU Profile and their customizations
Note: While developers can access multiple customizations through different Amazon Q Developer profiles, they only incur a single user subscription cost since they are using the organization instance of IAM Identity Center. This is because the subscription is tied to their user identity in the IAM Identity Center organization instance, not to the number of profiles or customizations they access.
Scenario 2 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account Similarly, developers from the Blue team can also configure multiple profiles:
One profile for accessing Alpha and Bravo customizations through the management account AWS IAM Identity Center instance
A separate profile for accessing Charlie customizations through the AWS IAM Identity Center member account Instance
When developers have access to multiple customizations within the same IAM Identity Center configuration and region, they can switch between profiles in their IDE without requiring reauthentication.
Figure 4 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Organization
However, as demonstrated in the blue developers’ case, switching between profiles that use different IAM Identity Center configurations (Organization vs Account Instance) still requires reauthentication.
Note: In this scenario, developers will incur two separate user subscription charges since they are accessing customizations through two different IAM Identity Center configurations (organization and account instance). As mentioned above, this scenario is not recommended except for situations it might make sense and is shown here purely to illustrate how the authentication and profile switching mechanisms work across different IAM Identity Center configurations.
Figure 5 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Account Instance
One scenario for creating code customizations specific to each profile is that the developers on the Alpha team might need Q to understand specific libraries and internal coding conventions for Java, while Bravo team developers might need Q to be well-versed in your proprietary technologies and development standards with Python. With separate profiles and customizations, each team gets their own “flavored” version of Q that understands their context.
For Blue developers who have access to Alpha, Bravo and Charlie customizations, they need to set up separate profiles since these customizations belong to different IAM Identity Center configurations and AWS Regions. Switching between these profiles requires reauthentication due to the different IAM Identity Center configurations involved.
Developer Team
AWS IAM Identity Center
Customizations
Orange
Organization instance
Alpha customizations in US East (N. Virginia)
Alpha customizations in EU Central (Frankfurt)
Blue
Organization instance
Alpha customizations in US East (N. Virginia)
Bravo customizations
Account instance
Charlie customizations
Grey
Organization instance
Bravo customizations
You can manage access to specific Amazon Q Developer Pro customizations by adding selected users and groups who already have access to Amazon Q Developer Pro subscriptions within the same Identity Center. This granular access control allows you to create targeted customizations that are only accessible to specific team members or groups within your organization.
Conclusion
In this post, we explored comprehensive strategies for implementing Amazon Q Developer customizations across large organizations. We demonstrated how Amazon Q Developer profiles provide a flexible way to manage access to different customizations across AWS regions and IAM Identity Center configurations. By integrating proprietary code repositories, establishing customization governance, and implementing continuous feedback loops, enterprises can maximize the value of their AI-powered development assistant while maintaining code quality and development standards.
The path forward depends on where you are in your Amazon Q Developer customization journey. If you’re just starting, begin with a clear assessment of your codebase and map out your customization approach before implementation. For existing users, review your current customizations and profile configurations to identify optimization opportunities.
In both cases, implement the customization governance we discussed, tailoring them to your specific development patterns and team structures. Remember that customization evolves with your codebase – regular refinements help ensure your AI assistant remains effective as your applications grow and development practices mature. Whether you’re new to Amazon Q Developer customizations or optimizing existing implementations, these practices can help develop an AI assistant that truly understands and aligns with your organization’s unique development environment.
Ready to get started? Visit the Amazon Q Developer guide to learn more about setting up profiles and customizations for your organization. If you need help planning your customization strategy, contact your AWS account team or find an AWS Partner in the AWS Partner Network.
Customers adopting Amazon Q Developer, a generative AI-powered coding companion, often need authentication through existing identity providers like PingIdentity. By leveraging AWS IAM Identity Center, organizations can enable their developers to access Amazon Q Developer with their existing PingIdentity credentials, streamlining authentication and removing the need for separate login procedures. Amazon Q Developer can chat about code, provide inline code completions, and generate new code. It also scans your code for security vulnerabilities and makes code improvements, including language updates, debugging, and optimizations. Amazon Q Developer comes in two tiers. The Free Tier is available at no cost for individual use. The Pro Tier is a paid version offering enterprise access controls, an analytics dashboard, customization, and higher usage limits. Organizations that enable the Pro tier of Amazon Q Developer for their developers typically authenticate with AWS IAM Identity Center. This approach is popular due to its ability to federate with external identity providers. In this blog, we will show you how to set up PingIdentity as an external IdP for IAM Identity Center and allow developers to access Amazon Q Developer using their existing PingIdentity login credentials.
How it works
Figure 1 – Solution Overview
The authentication workflow is as follows:
The developer initiates an access request to Amazon Q Developer.
IAM Identity center checks authentication status.
If not authenticated, redirects to PingIdentity login.
Developer provides PingIdentity Credentials.
PingIdentity validates credentials and sends SAML response.
IAM Identity Center verifies the SAML response.
Upon successful verification, grants Amazon Q Developer access.
Developer begins using Amazon Q Developer.
Prerequisites
AWS account
PingIdentity environment with users and groups already setup for Amazon Q Developer access
IAM identity center
Pro Tier subscription of Amazon Q Developer
Walkthrough
In this section, we demonstrate how to create a SAML-based connection between PingIdentity and IAM Identity Center, enabling you to access Amazon Q Developer seamlessly using your PingIdentity credentials.
Note: You will need to switch between PingIdentity portal and IAM Identity Center in your browser. We recommend opening a new browser tab for each console.
Step 1: Enable AWS Single Sign-On in PingIdentity
This step involves enabling AWS Single Sign-On application within PingIdentity.
In the PingIdentity console, Navigate to the Applications Tab > Application Catalog
Browse catalog for AWS Single Sign-On and select + to start the Quick Setup.
Figure 2 – PingIdentity Application Catalog
Alt Text: Screenshot of the PingIdentity Application Catalog interface. The search term “aws” is entered in the search bar, displaying three results: Amazon Web Services – AWS, AWS Gov-Cloud, and AWS Single Sign-On. The “AWS Single Sign-On” option is outlined with a red box and includes a plus button to add the application
Provide Name, SSO Region and SSO Tenant ID and choose Next
Name – Input an appropriate name for the connection
SSO Region – Input the appropriate region
Tenant ID – Identity Store ID You can run the following CLI command to retrieve the value. It’s a 10-digit alphanumeric prefixed by “d-“.
Navigate to PingOne Mappings and select Email Address from the drop down.
Figure 3 – AWS Single Sign-On attribute mapping
Alt Text: Screenshot of the AWS Single Sign-On configuration in PingIdentity. The screen shows Step 2 of the setup process where the SAML attribute SAML_SUBJECT is mapped to the PingOne attribute “Email Address”. A red box highlights the mapping section under “PingOne Mappings”.
Search and select the group that you have created earlier for enabling access to Amazon Q Developer and select + to add the group.
Choose Save
Figure 4 – Select PingIdentity directory Groups for Amazon Q Developer access
Alt Text: Screenshot of Step 3 in the AWS Single Sign-On setup process in PingIdentity. The screen shows the group selection interface where the “Amazon Q” group is listed. A plus icon is shown next to the group to add it, and a blue “Save” button is highlighted in the bottom-right corner to confirm the configuration.
Step 2: Connecting PingIdentity with IAM identity Center
This step involves configuring PingIdentity with the AWS IAM Identity Center sign-on details to complete the authentication setup.
In the PingIdentity console, Navigate to the Applications Tab > Applications and select the application you created earlier in Step 1
Select Enable Advanced Configuration and choose Enable.
Figure 5 – Enable Advanced configuration for AWS single Sign-On application
Alt Text: Screenshot of the PingIdentity Applications dashboard showing the AWS Single Sign-On application selected. The overview panel displays key configuration sections including protocol (SAML), mapped attributes, selected policies, and access group (Amazon Q). The option “Enable Advanced Configuration” is highlighted near the bottom of the panel.
Scroll down and select Download Metadata. This will save the Metadata file to your local computer, which you will use later during the configuration process.
Under Identity source, select Change identity source from the Actions drop-down menu.
Figure 6 – Change identity source in IAM Identity Center Console
Alt Text: Screenshot of the IAM Identity Center settings page, focused on the “Identity source” tab. The page displays details such as identity source, authentication method, AWS access portal URL, issuer URL, and identity store ID. A dropdown menu labeled “Actions” is expanded in the top-right corner, showing options to “Customize AWS access portal URL” and “Change identity source,” highlighted with a red box.
On the next page, select External identity provider and choose Next.
Under Service provider metadata copy the IAM Identity Center Assertion Consumer Service (ACS) URL.
Figure 7 – Copy IAM Identity Center ACS URL
Alt Text: Screenshot of the “Configure external identity provider” step in the AWS IAM Identity Center setup process. The screen displays service provider metadata including the AWS access portal sign-in URL, IAM Identity Center Assertion Consumer Service (ACS) URL (highlighted with a red box), and IAM Identity Center issuer URL. A button labeled “Download metadata file” is shown in the upper right.
Now go back to the PingIdentity browser tab and Navigate to the Configuration tab and select pencil icon to edit the details.
Paste the ACS URL you copied from the IAM identity center console and choose Save.
Figure 8 – Configuring AWS Single Sign-On SAML Settings in PingIdentity console
Alt Text: Two screenshots showing the configuration and editing of SAML settings for AWS Single Sign-On in PingIdentity. The first image displays the static configuration view, listing the ACS URL, signing key (“PingOne SSO Certificate for Administrators environment”), signing method (“Response”), and signing algorithm. The second image shows the editable configuration screen with the ACS URL input field highlighted in red, alongside dropdowns for selecting the signing key, options for signing method (Assertion, Response, or both), and the RSA_SHA256 signing algorithm. These screens guide users through setting up secure SAML integration with AWS SSO.
Step 3: Configure PingIdentity as external IdP in IAM identity Center
This step involves setting up PingIdentity as an external IdP in IAM Identity Center to enable federated access.
Navigate back to the previous browser tab where you had IAM Identity Center console open.
Upload the downloaded PingIdentity IdP SAML metadata file from step 3 of previous section and select Next.
Figure 9 – AWS IAM Identity Center metadata
Alt Text: Screenshot of the AWS Identity Center configuration screen where the user uploads the IdP SAML metadata XML file. The metadata file is shown as successfully selected. Below are empty fields for optional manual entry of IdP sign-in URL, IdP issuer URL, and IdP certificate. The “Next” button is highlighted in orange at the bottom right, indicating the next step in the setup process.
Review the list of changes. Once you are ready to proceed, type ACCEPT, then select Change identity source.
Step 4: Enable provisioning and identity-aware sessions in IAM identity Center
This step involves configuring user provisioning and enabling identity-aware sessions in AWS IAM Identity Center to support dynamic access control.
On the Settings page, locate and enable automatic provisioning. This immediately enabled automatic provisioning in IAM Identity Center and displays the necessary SCIM endpoint and access token information.
In the Inbound automatic provisioning dialog box, copy each of the values for the following options. You will need to paste these later when you configure provisioning in PingIdentity.
Figure 10 – IAM Identity Center Settings for identity aware sessions and automatic provisioning
Alt Text: Two options are displayed for further configuration: “Enable identity-aware sessions” and “Automatic provisioning.” Both options have an “Enable” button on the right-hand side, highlighted in red.
Step 5: Configure connections provisioning in PingIdentity
This step involves setting up connection provisioning in PingIdentity to enable automatic user and group management.
In the PingIdentity console, Navigate to the Integrations > Provisioning.
Select plus icon > New Connection
Under connection type Select Identity Store.
Figure 11 – PingIdentity connection provisioning
Alt Text: PingIdentity Provisioning configuration screen. The left sidebar highlights the “Provisioning” tab. The main panel shows the “Create a New Connection” dialog with two connection type options: “Identity Store” and “Gateway.” The “Identity Store” option is selected using the “Select” button on the right. A plus (+) icon at the top indicates the option to add a new provisioning connection.
Select SCIM outbound from the list of options and select Next.
Provide a name for the connection and select Next.
Paste the SCIM endpoint URL into the SCIM BASE URL field.
Navigate to Authentication Method and select OAuth 2 Bearer Token.
Paste the Access token into the Oauth Access Token field.
Select Test Connection to validate the connectivity and select Next.
Figure 12 – Configure authentication details
Alt Text: PingIdentity interface showing the “Configure Authentication” step in the “Create a New Connection” wizard. Key fields include the SCIM Base URL, SCIM Version (2.0), Authentication Method (OAuth 2 Bearer Token), OAuth Access Token (obscured), and resource paths for Users and Groups. The “Test Connection” and “Next” buttons are visible at the bottom.
Navigate to User Filter Expression and change to userName Eq “%s”.
Choose Save. By default, the connection is created in a Disabled state.
Figure 13 – Edit UserFilter Expressions for the connection
Alt Text: Final step in the PingIdentity “Create a New Connection” wizard showing the “Configure Preferences” screen. The highlighted fields include “User Filter Expression” with the value userName Eq “%s”, “User Identifier” set to userName, and group membership handling options (“Merge” and “Overwrite” with “Overwrite” selected). A “Save” button is highlighted at the bottom right.
Select the connection you created and select the toggle switch to enable the connection.
Figure 14 – Enable the connection
Alt Text: PingIdentity configuration screen showing the IAM Identity Store integration. The page displays the identity store name, and tabs for “Overview” and “Configuration.” A toggle switch in the top-right corner is highlighted, indicating the integration is currently enabled.
Step 6: Configure rules provisioning in PingIdentity
This step involves setting up provisioning rules in PingIdentity to define how users and groups are synchronized.
In the PingIdentity console, Navigate to the Integrations > Provisioning.
Select plus icon > New Rule
Provide a Name and Description for the rule.
Choose Create.
Select plus icon to select the Connection you created in the previous step.
Choose Save.
Figure 15 – Add the IAM identity center connection to the rule
Alt Text: Screenshots showing the final steps in connecting the IAM Identity Center to the IAM identity store using PingIdentity. The first image shows the IAM Identity Store connection listed under “Available Connections” with a plus (+) icon to initiate the link. The second image shows the selected connection from the PingOne Directory (P1) as the source and IAM identity store (SCIM) as the target, with the option to “Save” the configuration.
If you want to sync users from your PingIdentity directory, create a user filter. To do so, navigate to User Filter and select pencil icon to edit the settings.
Choose the appropriate filter from the drop down based on your use case and select Save. I have chosen Group Name which has been designated for Amazon Q Developer access.
Figure 16 – PingIdentity user filter
Alt Text: Screenshot of the “Edit User Filter” interface in IAM Identity Center. The user filter is configured to provision users who belong to a group with names that contain “Amazon Q Developer.” The condition logic is set to match if “Any” of the conditions are true.
If you want to sync a group from your PingIdentity directory, create group provisioning. To do so, navigate to Group Provisioning and select pencil icon to edit the settings.
Select the appropriate group which has been designated for Amazon Q Developer access and choose Save.
Figure 17 – PingIdentity Group Provisioning
Alt Text: Screenshot of the “Edit Group Provisioning” screen in IAM Identity Center. The group “Amazon Q Developer” is selected for outbound provisioning. A “Save” button is highlighted in the bottom-left corner.
Navigate to Attribute Mapping and select the pencil icon to edit the settings.
Delete the PingOne Directory attribute Primary Phone.
Add a new attribute and select Username as PingOne Directory and displayName as IAM identity Store.
Choose Save.
Figure 18 – PingIdentity attribute mapping
Alt Text: Two screenshots showing the editing of attribute mappings in IAM Identity Center. The first image displays default mappings such as ‘Email Address’ to ‘workEmail’ and ‘Username’ to ‘userName’, with an option to delete or update each field. The second image shows the addition of a new attribute mapping from ‘Username’ to ‘displayName’, along with highlighted ‘Add’ and ‘Save’ buttons.
Select the rule you created and select the toggle switch to enable the rule.
This automatically provisions the users/groups from PingIdentity to IAM identity Center using SCIM.
Figure 19 – PingIdentity Users and Groups Sync status using SCIM
Alt Text: IAM Identity Center sync summary showing successful user and group provisioning. The first image highlights two users impacted and successfully synced. The second image highlights one group impacted and successfully synced. Sync status is marked ‘ACTIVE’ in both views, confirming successful integration between PingOne and AWS IAM Identity Center.
Step 7: Provide access to Amazon Q Developer
This step involves locating and subscribing the groups that need permission to use Amazon Q Developer.
In the Amazon Q Developer console, under Subscriptions add the IAM identity center groups which require access to Amazon Q Developer.
Select Subscribe and search for the group name.
Select Assign.
Figure 20 – Amazon Q Developer subscriptions page
Alt Text: Screenshot of the Amazon Q Developer Subscriptions page in the AWS Management Console. The “Groups” tab is selected, displaying “Amazon Q Developer,” with a subscription status of “Subscribed.” The “Amazon Q Developer” group is highlighted with a red box.
Setup Amazon Q Developer with IAM Identity Center
This section guides you through installing the Amazon Q Developer extension and setting up authentication with IAM Identity Center.
To set up Amazon Q Developer extension in your integrated development environment (IDE), complete the steps in AWS documentation.
Once extension is installed Choose Amazon Q icon in your IDE.
Choose a sign-in option.
Select Use with Pro license and choose
Continue.
Provide the Start URL. You can retrieve this AWS access portal URL from the IAM Identity Center Console.
Figure 21 – IAM identity center access portal URL
Alt Text: Screenshot of the IAM Identity Center settings page in the AWS Console, displaying the identity source configuration. It shows that the identity source is set to “External identity provider” with SAML 2.0 authentication and SCIM provisioning. The highlighted section includes the AWS access portal URL and the Identity Store ID. The “Settings” tab is selected in the left navigation pane.
Provide the region that hosts the identity directory and choose Continue
Select Open on the resulting pop up which redirects to your browser.
The browser redirects you to the Pingone URL where you enter your PingIdentity credentials and select Sign On.
Upon successful authentication, select Allow access on the resulting pop up to login successfully.
Alt Text: A screen recording of Visual Studio Code where the user selects the Amazon Q icon from the sidebar. The screen transitions to a login prompt indicating that the user must authenticate using their PingIdentity credentials via IAM Identity Center before accessing Amazon Q Developer features. The message highlights that authentication is required to continue.
Test Configuration
Upon successfully completing the previous step, you can now leverage the code suggestions by Amazon Q Developer.
Figure 23 – Amazon Q Developer example
Alt Text: A screen recording of Visual Studio Code where Amazon Q Developer generates a sample code inline.
Clean Up
To avoid ongoing charges after testing this solution, follow these steps to remove all provisioned resources:1. Remove PingIdentity Application Configuration
In the PingIdentity console, navigate to Applications.
Locate and delete the AWS Single Sign-On application that was configured for IAM Identity Center integration.
2. Reset IAM Identity Center Configuration
In the AWS IAM Identity Center console:
Navigate to Settings > Identity source.
Change the identity source back to the default IAM Identity Center directory if no longer using PingIdentity.
Remove any external metadata and configuration uploaded during the setup.
3. Revoke Subscriptions and Access
In the Amazon Q Developer console:
Go to Subscriptions and remove assigned groups such as Amazon Q Developer or code whisperer trial.
This will deactivate access and prevent any future charges tied to those subscriptions.
4. Remove Amazon Q Developer Extension
If desired, uninstall the Amazon Q Developer extension from Visual Studio Code to fully revert the development environment.
Conclusion
In this post, we demonstrated how to use existing PingIdentity credentials to access Amazon Q Developer through integration with IAM Identity Center. We provided a step-by-step guide for configuring PingIdentity as an external identity provider (IdP) with IAM Identity Center. Lastly, we demonstrated how to connect Amazon Q Developer extension within your IDE to AWS using your PingIdentity credentials, allowing seamless access to Amazon Q Developer.If you have any comments or questions, share them in the comments section.
Sid Vantair is a Solutions Architect with AWS covering Strategic accounts. He thrives on resolving complex technical issues to overcome customer hurdles. Outside of work, he cherishes spending time with his family and fostering inquisitiveness in his children.
Amazon Managed Streaming for Apache Kafka (MSK) Connect is a fully managed, scalable, and highly available service that enables the streaming of data between Apache Kafka and other data systems. Amazon MSK Connect is built on top of Kafka Connect, an open-source framework that provides a standard way to connect Kafka with external data systems. Kafka Connect supports a variety of connectors, which are used to stream data in and out of Kafka. MSK Connect extends the capabilities of Kafka Connect by providing a managed service with added security features, straightforward configuration, and automatic scaling capabilities, enabling businesses to focus on their data streaming needs without the overhead of managing the underlying infrastructure.
In some use cases, you might need to use an MSK cluster in one AWS account, but MSK Connect is located in a separate account. In this post, we demonstrate how to create a connector to achieve this use case. At the time of writing, MSK Connect connectors can be created only for MSK clusters that have AWS Identity and Access Management (IAM) role-based authentication or no authentication. We demonstrate how to implement IAM authentication after establishing network connectivity. IAM provides enhanced security measures, making sure your systems are protected against unauthorized access.
Solution overview
The connector can be configured for a variety of purposes, such as sinking data to an Amazon Simple Storage Service (Amazon S3) bucket, tracking the source database changes, or serving as a migration tool such as MirrorMaker2 on MSK Connect to transfer data from a source cluster to a target cluster this is located in a different account.
The following diagram illustrates a use case using Debezium and Amazon S3 source connectors.
The following diagram illustrates using S3 Sink and migration to a cross-account failover cluster using a MirrorMaker connector deployed on MSK Connect.
Currently MSK Connect connectors can be created only for MSK clusters which have IAM role-based authentication or no authentication. In this blog, I’ll guide you through the essential steps for implementing the industry-recommended IAM (Identity and Access Management) authentication after establishing network connectivity. IAM provides enhanced security measures, ensuring your systems are protected against unauthorized access.
The launch of multi-VPC private connectivity (powered by AWS PrivateLink) and cluster policy support for MSK clusters simplifies the connectivity of Kafka clients to brokers. By enabling this feature on the MSK cluster, you can use the cluster-based policy to manage all access control centrally in one place. In this post, we cover the process of enabling this feature on the source MSK cluster.
We don’t fully utilize the multi-VPC connectivity provided by this new feature because that requires you to use different bootstrap URLs with port numbers (14001:3) that are not supported by MSK Connect as of writing of this post. We explore a secure network connectivity solution that uses private connectivity patterns, as detailed in How Goldman Sachs builds cross-account connectivity to their Amazon MSK clusters with AWS PrivateLink.
Connecting to a cross-account MSK cluster from MSK Connect involves the following steps.
Steps to configure the MSK cluster in Account A:
Enable the multi-VPC private connectivity(Private Link) feature for IAM authentication scheme that is enabled for your MSK cluster.
Configure the cluster policy to allow a cross-account connector.
Implement one of the preceding network connectivity patterns according to your use case to establish the connectivity with the Account B VPC and make network changes accordingly.
Steps to configure the MSK connector in Account B:
Verify the network connectivity from Account A and make network changes accordingly.
Check the destination service to verify the incoming data.
Prerequisites
To follow along with this post, you should have an MSK cluster in one AWS account and MSK Connect in a separate account.
Set up the MSK cluster setup in Account A:
In this post, we only show the important steps that are required to enable the multi-VPC feature on an MSK cluster:
Create a provisioned MSK cluster in Account A’s VPC with the following considerations, which are required for the multi-VPC feature:
Cluster version must be 2.7.1 or higher.
Instance type must be m5.large or higher.
Authentication should be IAM (you must not enable unauthenticated access for this cluster).
After you create the cluster, go to the Networking settings section of your cluster and choose Edit. Then choose Turn on multi-VPC connectivity.
Select IAM role-based authentication and choose Turn on selection.
It might take around 30 minutes to enable. This step is required to enable the cluster policy feature that allows the cross-account connector to access the MSK cluster.
After it has been enabled, scroll down to Security settings and choose Edit cluster policy.
Define your cluster policy and choose Save changes.
The new cluster policy allows for defining a Basic or Advanced cluster policy. With the Basic option, it only allows CreateVPCConnection, GetBootstrapBrokers, DescribeCluster, and DescribeClusterV2 actions that are required for creating the cross-VPC connectivity to your cluster. However, we have to use Advanced to allow more actions that are required by the MSK Connector. The policy should be as follows:
You might need to modify the preceding permissions to limit access to your resources (topics, groups). Also, you can restrict access to a specific connector by giving the connector IAM role, or you can mention the account number to allow the connectors in that account.
Now the cluster is ready. However, you need to make sure of the network connectivity between the cross-account connector VPC and the MSK cluster VPC.
If you’re using VPC peering or Transit Gateway while connecting to MSK Connect either from cross-account or the same account, do not configure your connector to reach the peered VPC resources with IPs in the following CIDR ranges (for more details, see Connecting from connectors):
10.99.0.0/16
192.168.0.0/16
172.21.0.0/16
In the MSK cluster security group, make sure you allowed port 9098 from Account B network resources and make changes in the subnets according to your network connectivity pattern.
Set up the MSK connector in Account B:
In this section, we demonstrate how to use the S3 Sink connector. However, you can use a different connector according to your use case and make the changes accordingly.
Create an S3 bucket (or use an existing bucket).
Make sure that the VPC that you’re using in this account has a security group and private subnets. If your connector for MSK Connect needs access to the internet, refer to Enable internet access for Amazon MSK Connect.
Verify the network connectivity between Account A and Account B by using the telnet command to the broker endpoints with port 9098.
Create a connector plugin according to your connector plugin provider (confluent or lenses). Make a note of the custom plugin Amazon Resource Name (ARN) to use in a later step.
Create an IAM role for your connector to allow access to your S3 bucket and the MSK cluster.
The IAM role’s trust relationship should be as follows:
You might need to modify the preceding permissions to limit access to your resources (topics, groups)
Finally, it’s time to create the MSK connector. Because the Amazon MSK console doesn’t allow viewing MSK clusters in other accounts, we show you how to use the AWS CLI instead. We also use basic Amazon S3 configuration for testing purposes. You might need to modify the configuration according to your connector’s use case.
Create a connector using the AWS CLI with the following command with the required parameters of the connector, along with Account A’s MSK cluster broker endpoints:
After you create the connector, connect the producer to your topic and insert data into it. In the following code, we use a Kafka client to insert data for testing purposes:
If everything is set up correctly, you should see the data in your destination S3 bucket. If not, check the troubleshooting tips in the following section.
Troubleshooting tips
After deploying the connector, if it’s in the CREATING state on the connector details page, access the Amazon CloudWatch log group specified in your connector creation request. Review the logs for any errors. If no errors are found, wait for the connector to complete its creation process.
Additionally, make sure the IAM roles have their required permissions, and check the security groups and NACLs for proper connectivity between VPCs.
Clean up
When you’re done testing this solution, clean up any unwanted resources to avoid ongoing charges
Conclusion
In this post, we demonstrated how to create an MSK connector when you need to use an MSK cluster in one AWS account, but MSK Connect is located in a separate account. This architecture includes an S3 Sink connector for demonstration purposes, but it can accommodate other types of sink and source connectors. Additionally, this architecture focuses solely on IAM authenticated connectors. If an unauthenticated connector is desired, the multi-VPC connectivity (PrivateLink) and cluster policy components can be ignored. The remaining process, which involves creating a network connection between the account VPCs, remains the same.
Try out the solution for yourself, and let us know your questions and feedback in the comments section.
Venkata Sai Mahesh Swargam is a Cloud Engineer at AWS in Hyderabad. He specializes in Amazon MSK and Amazon Kinesis services. Mahesh is dedicated to helping customers by providing technical guidance and solving issues related to their Amazon MSK architectures. In his free time, he enjoys being with family and traveling around the world.
Today, we’re announcing the general availability of a new capability that integrates AWS Backup logically air-gapped vaults with Multi-party approval to provide access to your backups even when your AWS account is inaccessible due to inadvertent or malicious events. AWS Backup is a fully managed service that centralizes and automates data protection across AWS services and hybrid workloads. It provides core data protection features, ransomware recovery capabilities, and compliance insights and analytics for data protection policies and operations.
As a backup administrator, you use AWS Backup logically air-gapped vaults to securely share backups across accounts and organizations, logically isolate your backup storage, and support direct restore to help reduce recovery time following an inadvertent or malicious event. However, if a bad or unintended actor gains root access to your backup account or the management account of your organization, your backups suddenly become inaccessible, even though they’re still safely stored in the logically air-gapped vault. While traditional account recovery involved working through support channels, AWS Backup with Multi-party approval delivers immediate access to recovery tools, empowering you with faster resolution times and greater control over your recovery timeline.
Multi-party approval for AWS Backup logically air-gapped vaults adds an additional layer of protection for you to recover your application data even when your AWS account becomes completely inaccessible. Using Multi-party approval, you can create approval teams which consist of highly trusted individuals in your organization, then associate them with your logically air-gapped vault. If you get locked out of your AWS accounts due to inadvertent or malicious actions, you can request your own approval team to authorize sharing of your vault from any account, even those outside your AWS Organizations account. Once approved, you gain authorized access to your backups and can begin your recovery process.
How it works Multi-party approval for AWS Backup logically air-gapped vaults combines the security of logically air-gapped vaults with the governance of Multi-party approval to create a recovery mechanism that works even when your AWS account is compromised. Here’s how it works:
1. Approval team creation First, you create an approval team in your AWS Organizations management account. If the management account is new, first create an AWS Identity and Access Management (IAM) Identity Center instance before creating the approval team. The approval team consists of trusted individuals (IAM Identity Center users) who will be authorized to approve vault sharing requests. Each approver receives an invitation to join the approval team through a new Approval portal.
2. Vault association When your approval team is active, you share it with accounts that own logically air-gapped vaults using AWS Resource Access Manager (AWS RAM) to safeguard against requests for approval from arbitrary accounts. Backup administrators can then associate this approval team with new or existing logically air-gapped vaults.
3. Protection against compromise If your AWS account becomes compromised or inaccessible, you can request access to your backups from a different account (a clean recovery account). This request includes the Amazon Resource Name (ARN) of the logically air-gapped vault in the format arn:aws:backup:<region>:<account>:backup-vault:<name> and an optional vault name and comment.
4. Multi-party approval The request is sent to the approval team, who review it through the approval portal. When the minimum required number of approvers authorize the request, the vault is automatically shared with the requesting account. All requests and approvals are comprehensively logged in AWS CloudTrail.
5. Recovery process With access granted, you can immediately start restoring or copying your data in the new recovery account without waiting for your compromised account to be remediated.
This approach provides an entirely separate authentication path to access and recover your backups, completely independent of your AWS account credentials. Even if the bad actor has root access to your account, they can’t prevent the approval team-based recovery process.
1. Create a new logically air-gapped vault To create a new logically air-gapped vault, provide a name, tags (optional), and vault lock properties. 2. Assign an approval team When the vault has been created, choose Assign approval team to assign it with an existing approval team.
Choose an existing approval team from the drop-down menu then select Submit to finalize the assignment.
Now your approval team is assigned to your logically air-gapped vault.
Good to know It’s essential to test your recovery process before an actual emergency:
From a different AWS account, use the AWS Backup console or API to request sharing of your logically air-gapped vault by providing the vault ID and ARN.
Request approval of your request from the approval team.
Once approved, verify that you can access and restore backups from the vault in your testing account.
As a best practice, monitor the health of your approval team regularly using AWS Backup Audit Manager to ensure they have sufficient active participants to meet your approval threshold.
Multi-party approval for enhanced cloud governance Today, we’re also announcing the general availability of a new capability that AWS account administrators can use to add Multi-party approval to their product offerings. As highlighted in this post, AWS Backup is the first service to integrate this capability. With Multi-party approval, administrators can enable application owners to guard sensitive service operations with a distributed review process.
Good to know Multi-party approval provides several significant security advantages:
Distributed decision-making, eliminating single points of failure
Full auditability through AWS CloudTrail integration
Protection against compromised credentials
Formal governance for compliance-sensitive operations
Consistent approval experience across integrated services
Now available
Multi-party approval is available today in all AWS Regions where AWS Organizations is available. Multi-party approval for AWS Backup logically air-gapped vaults is available in all AWS Regions where AWS Backup is available.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
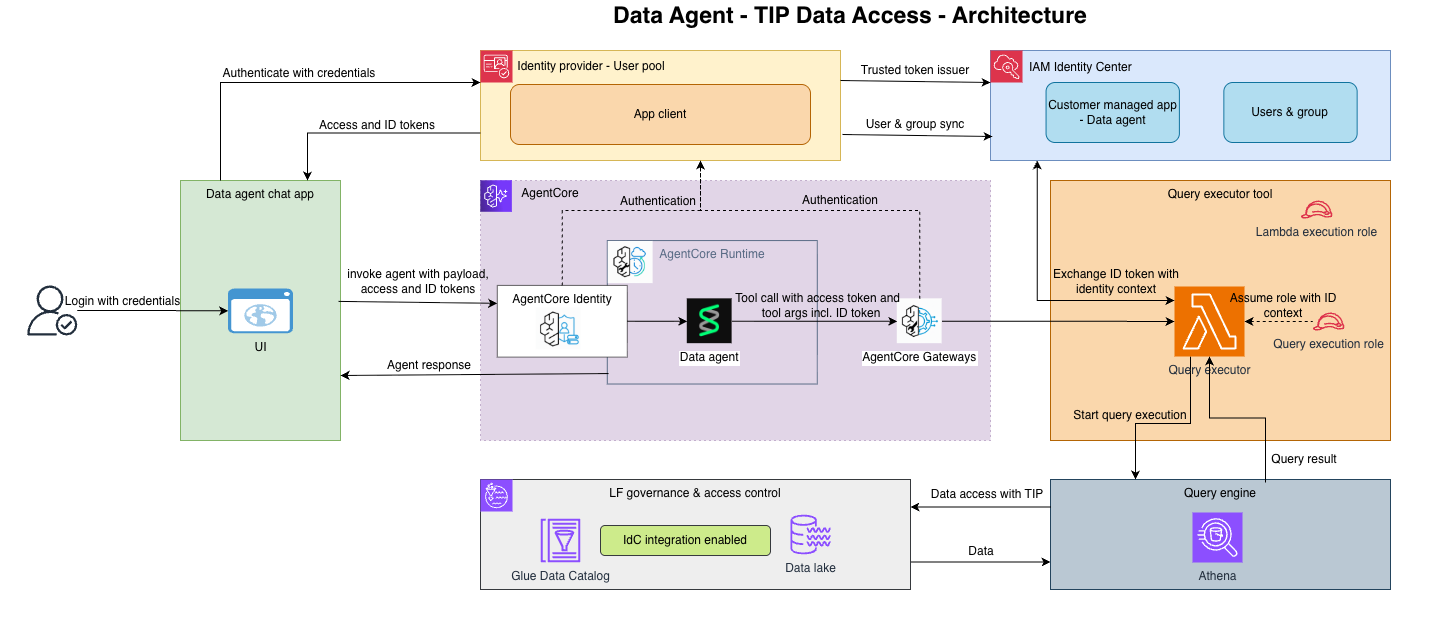
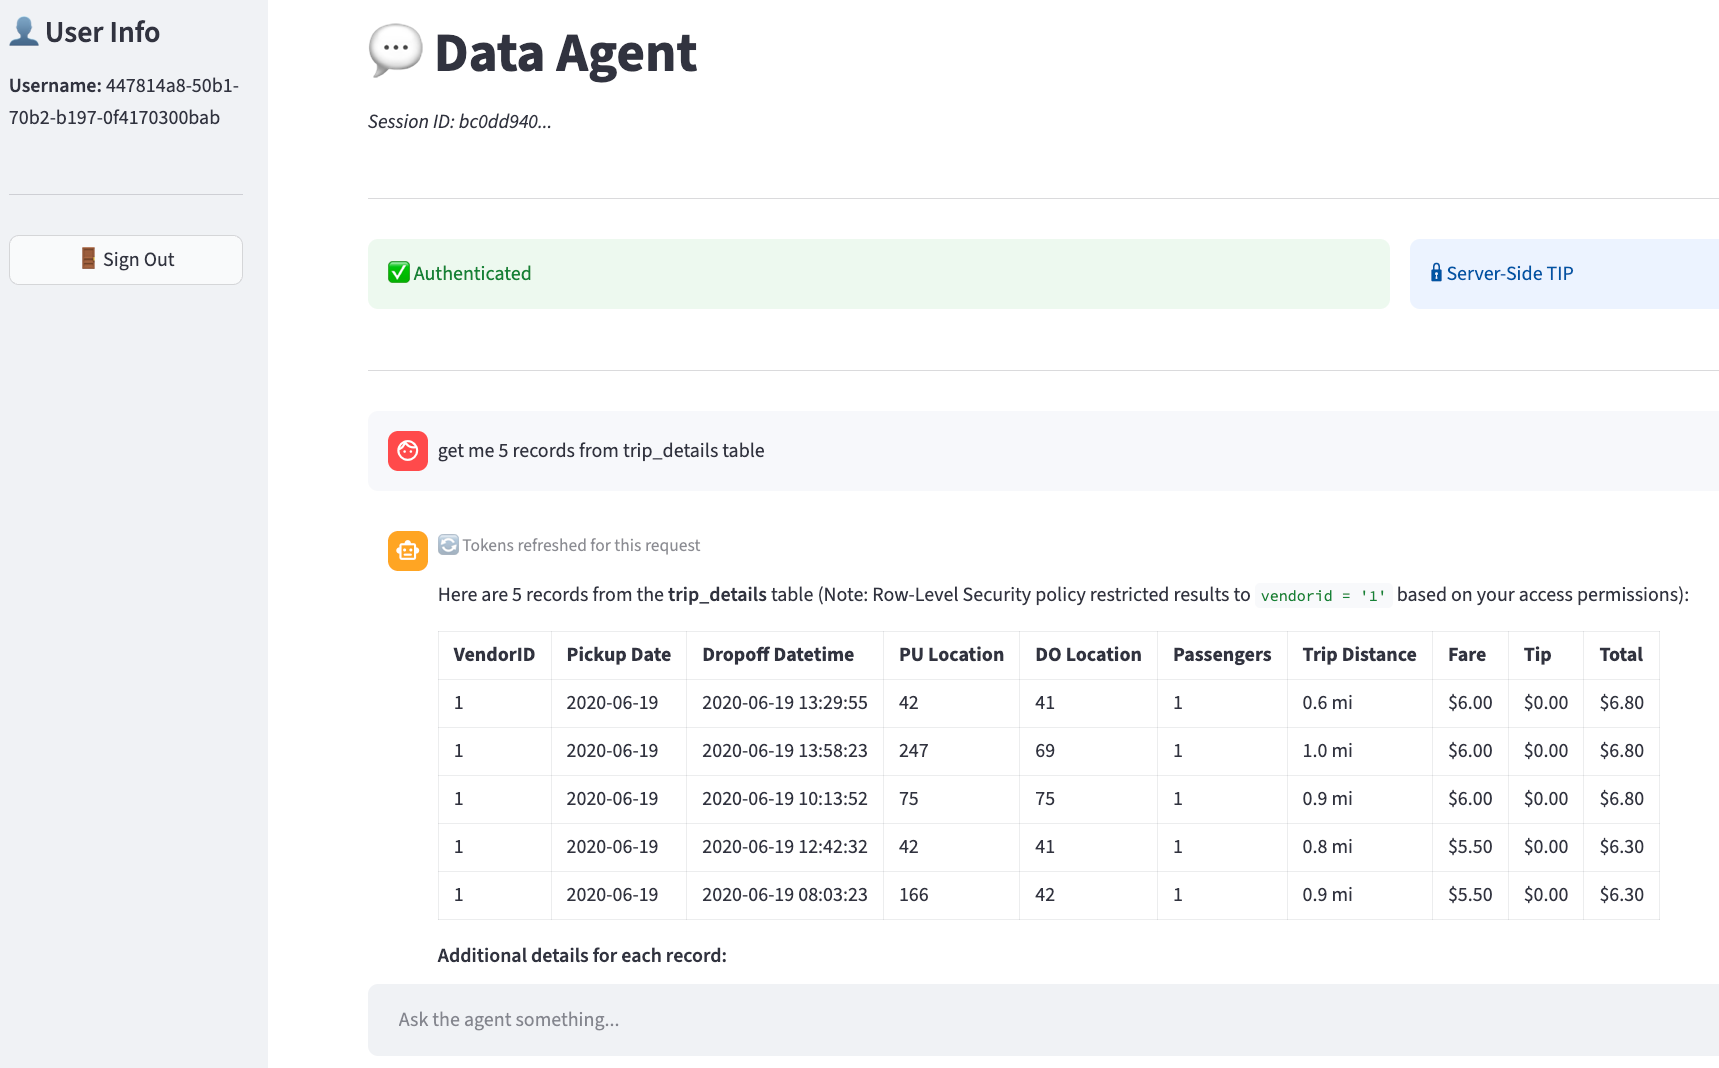
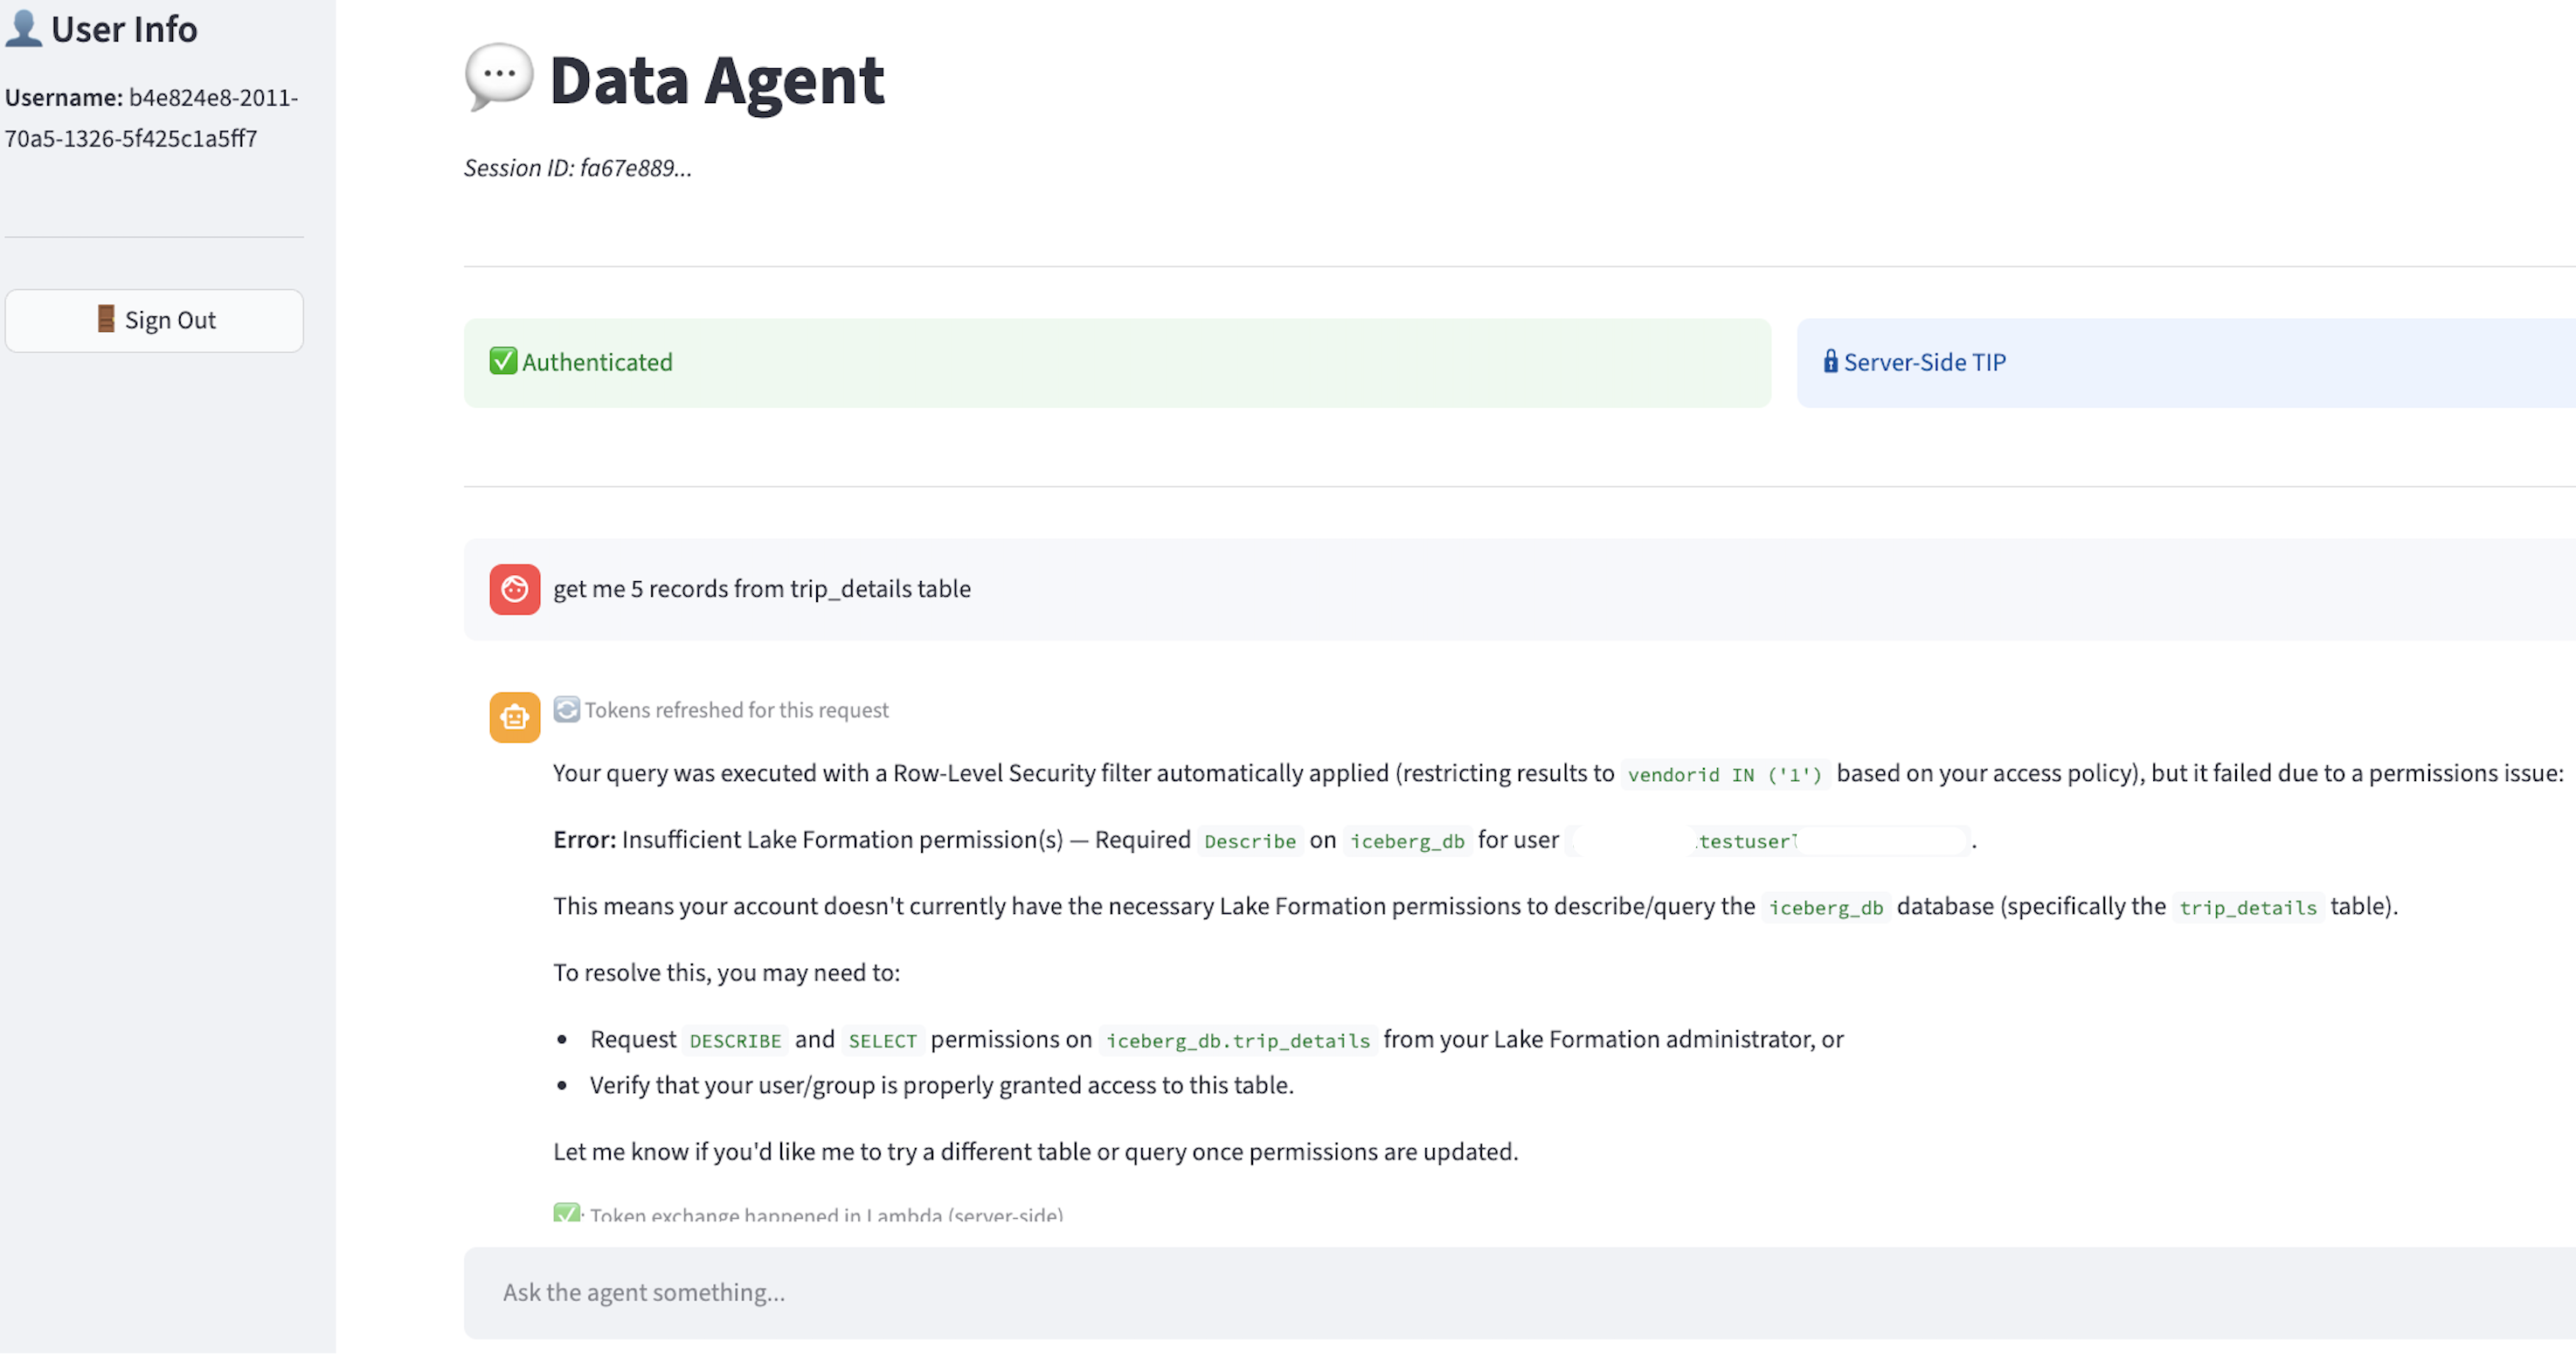
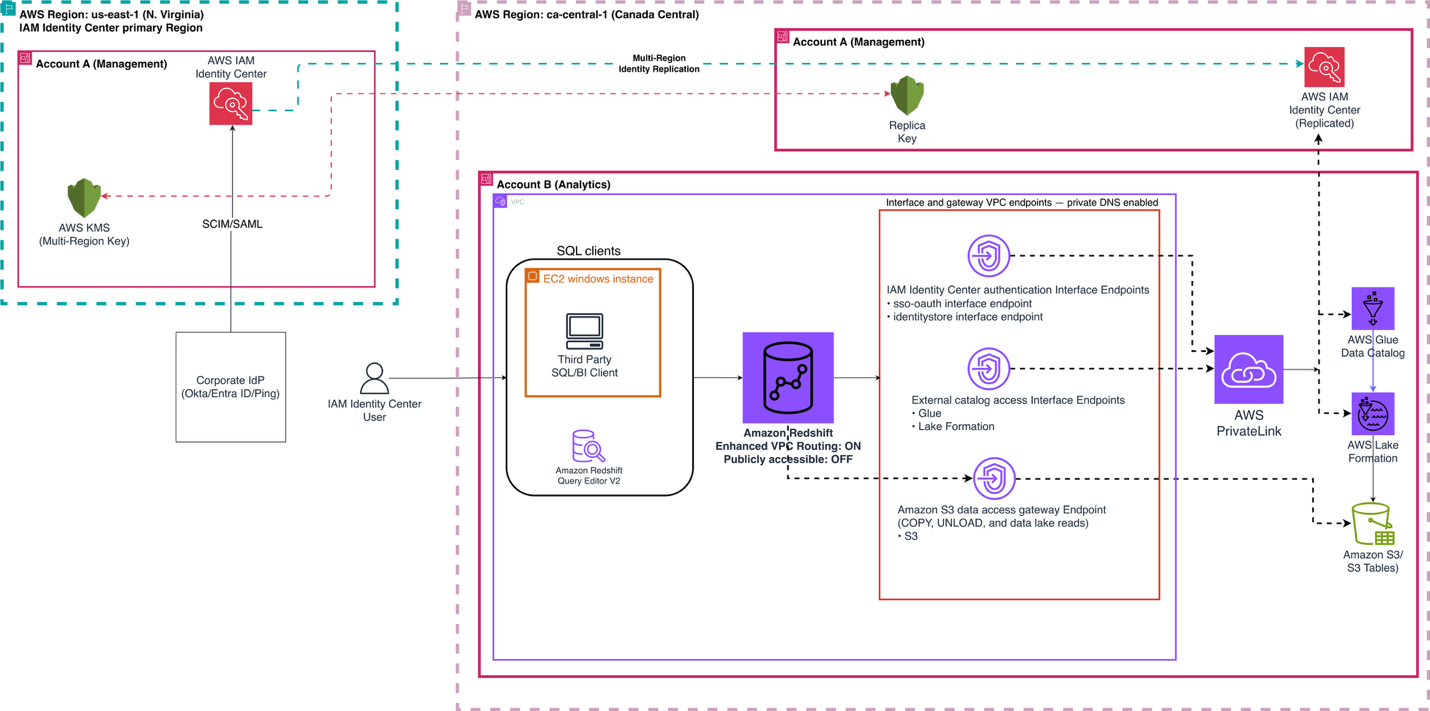
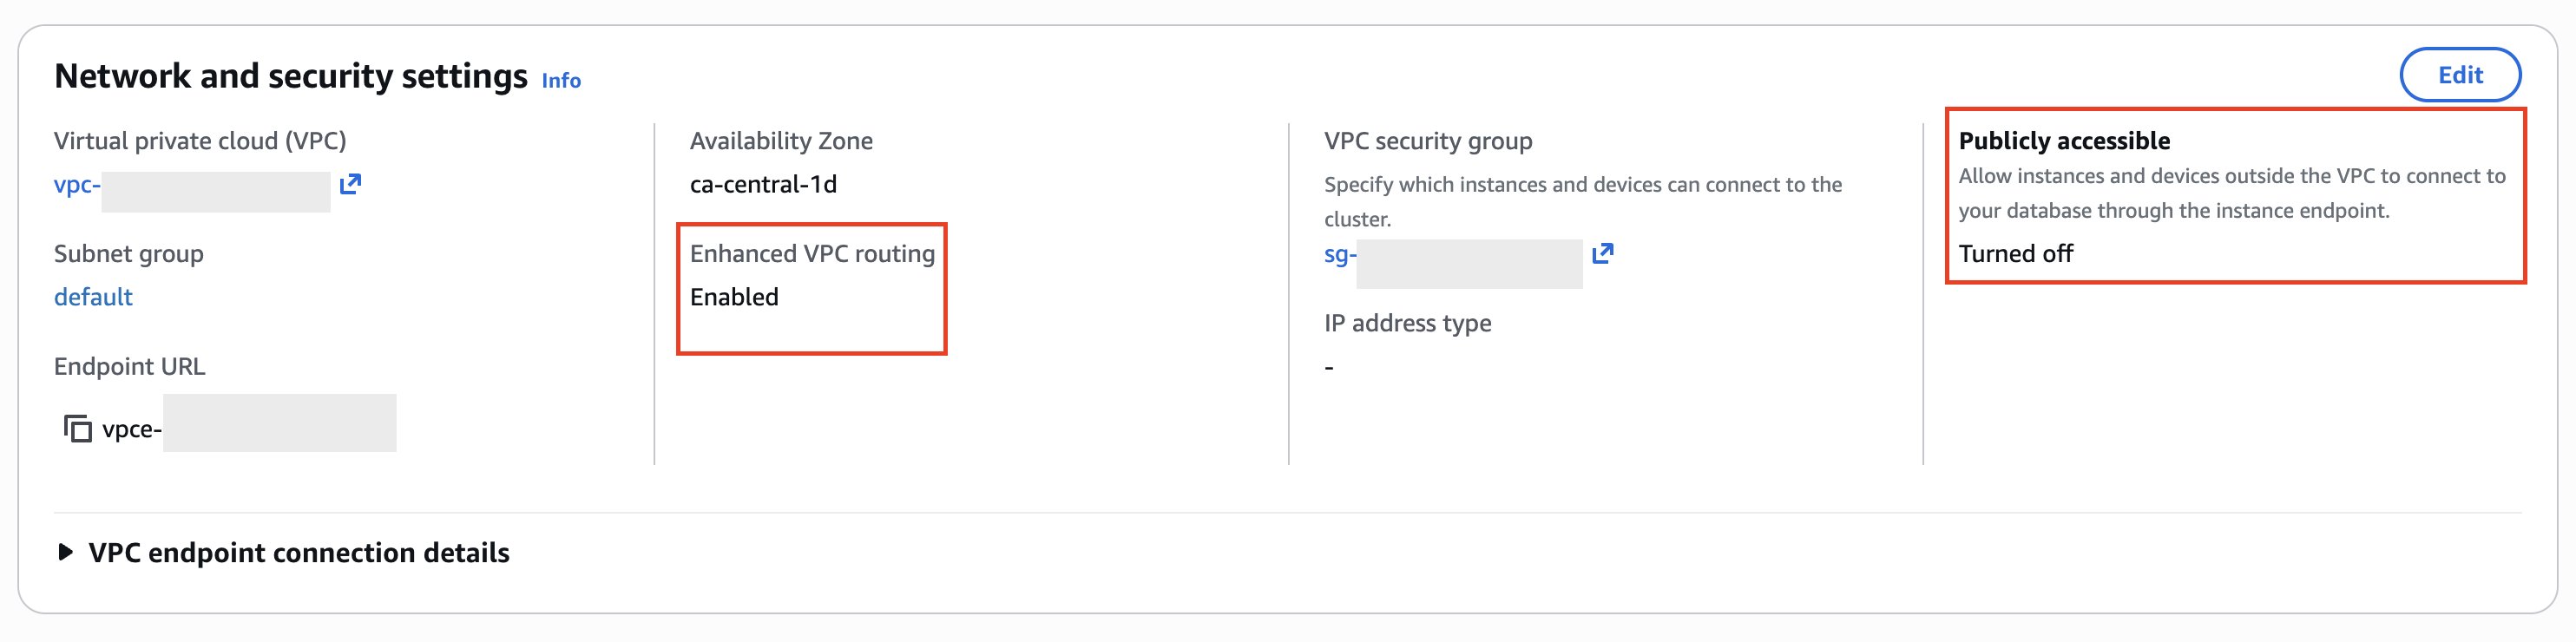
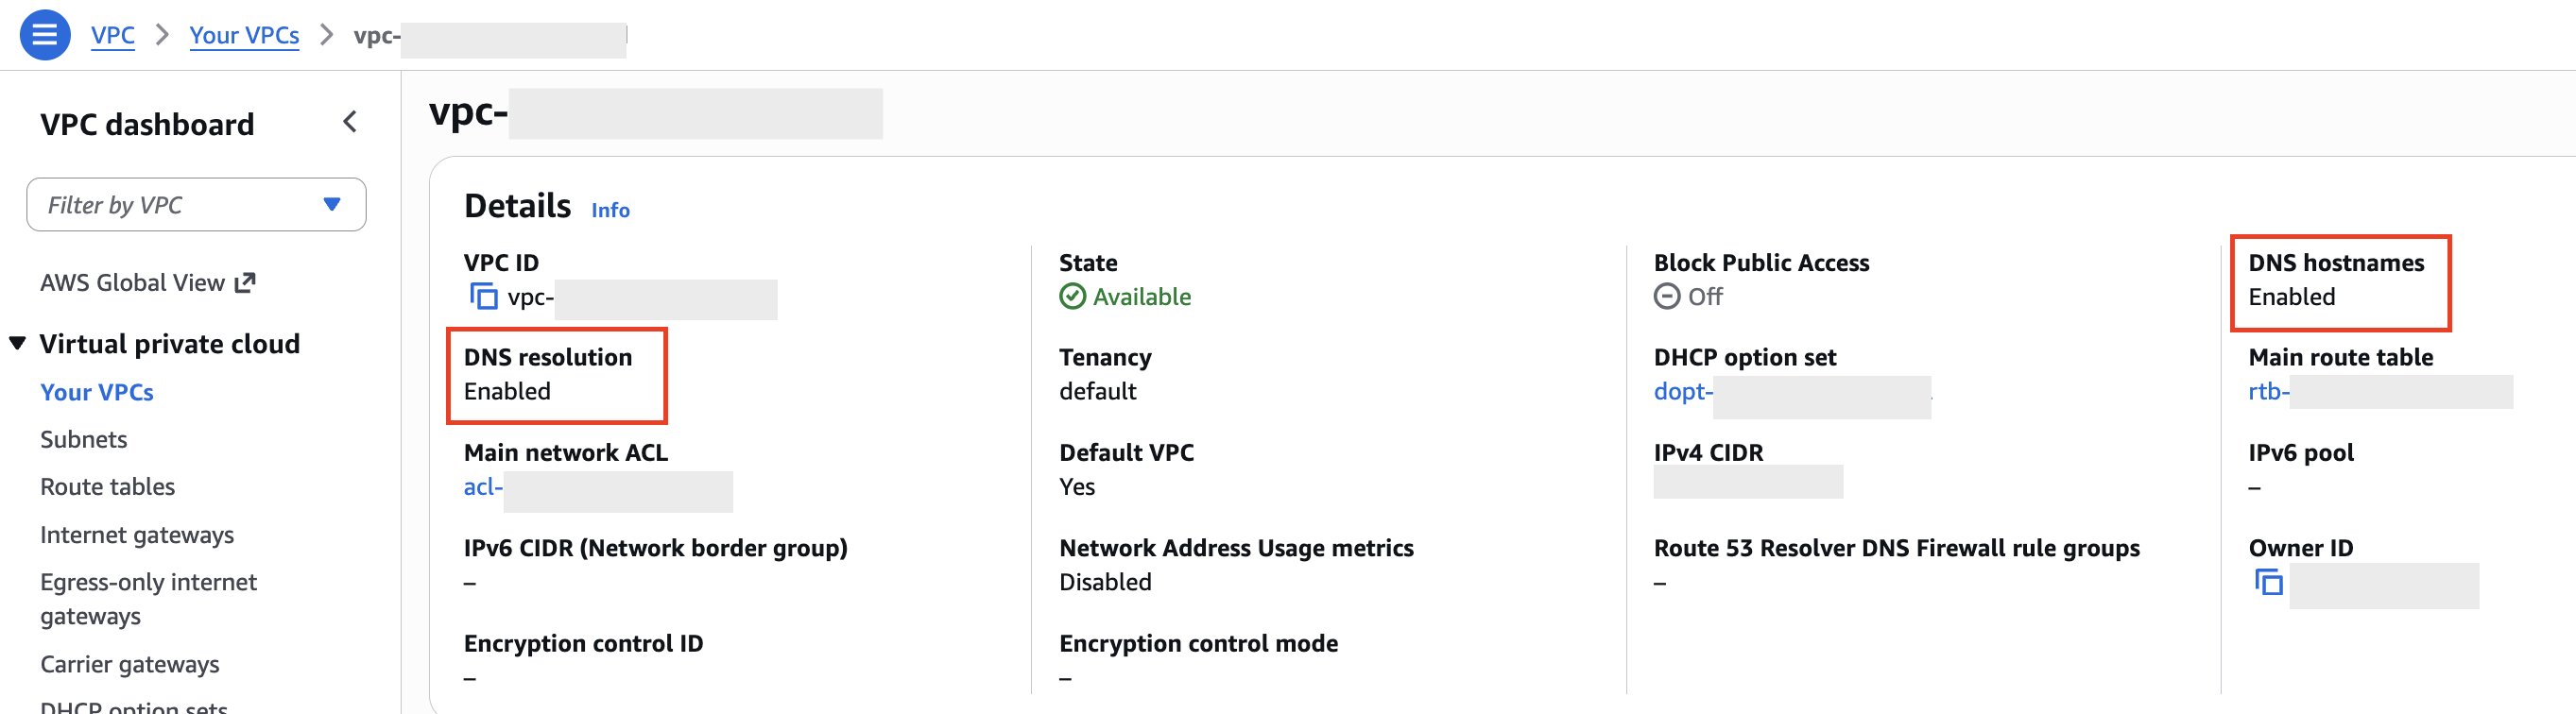
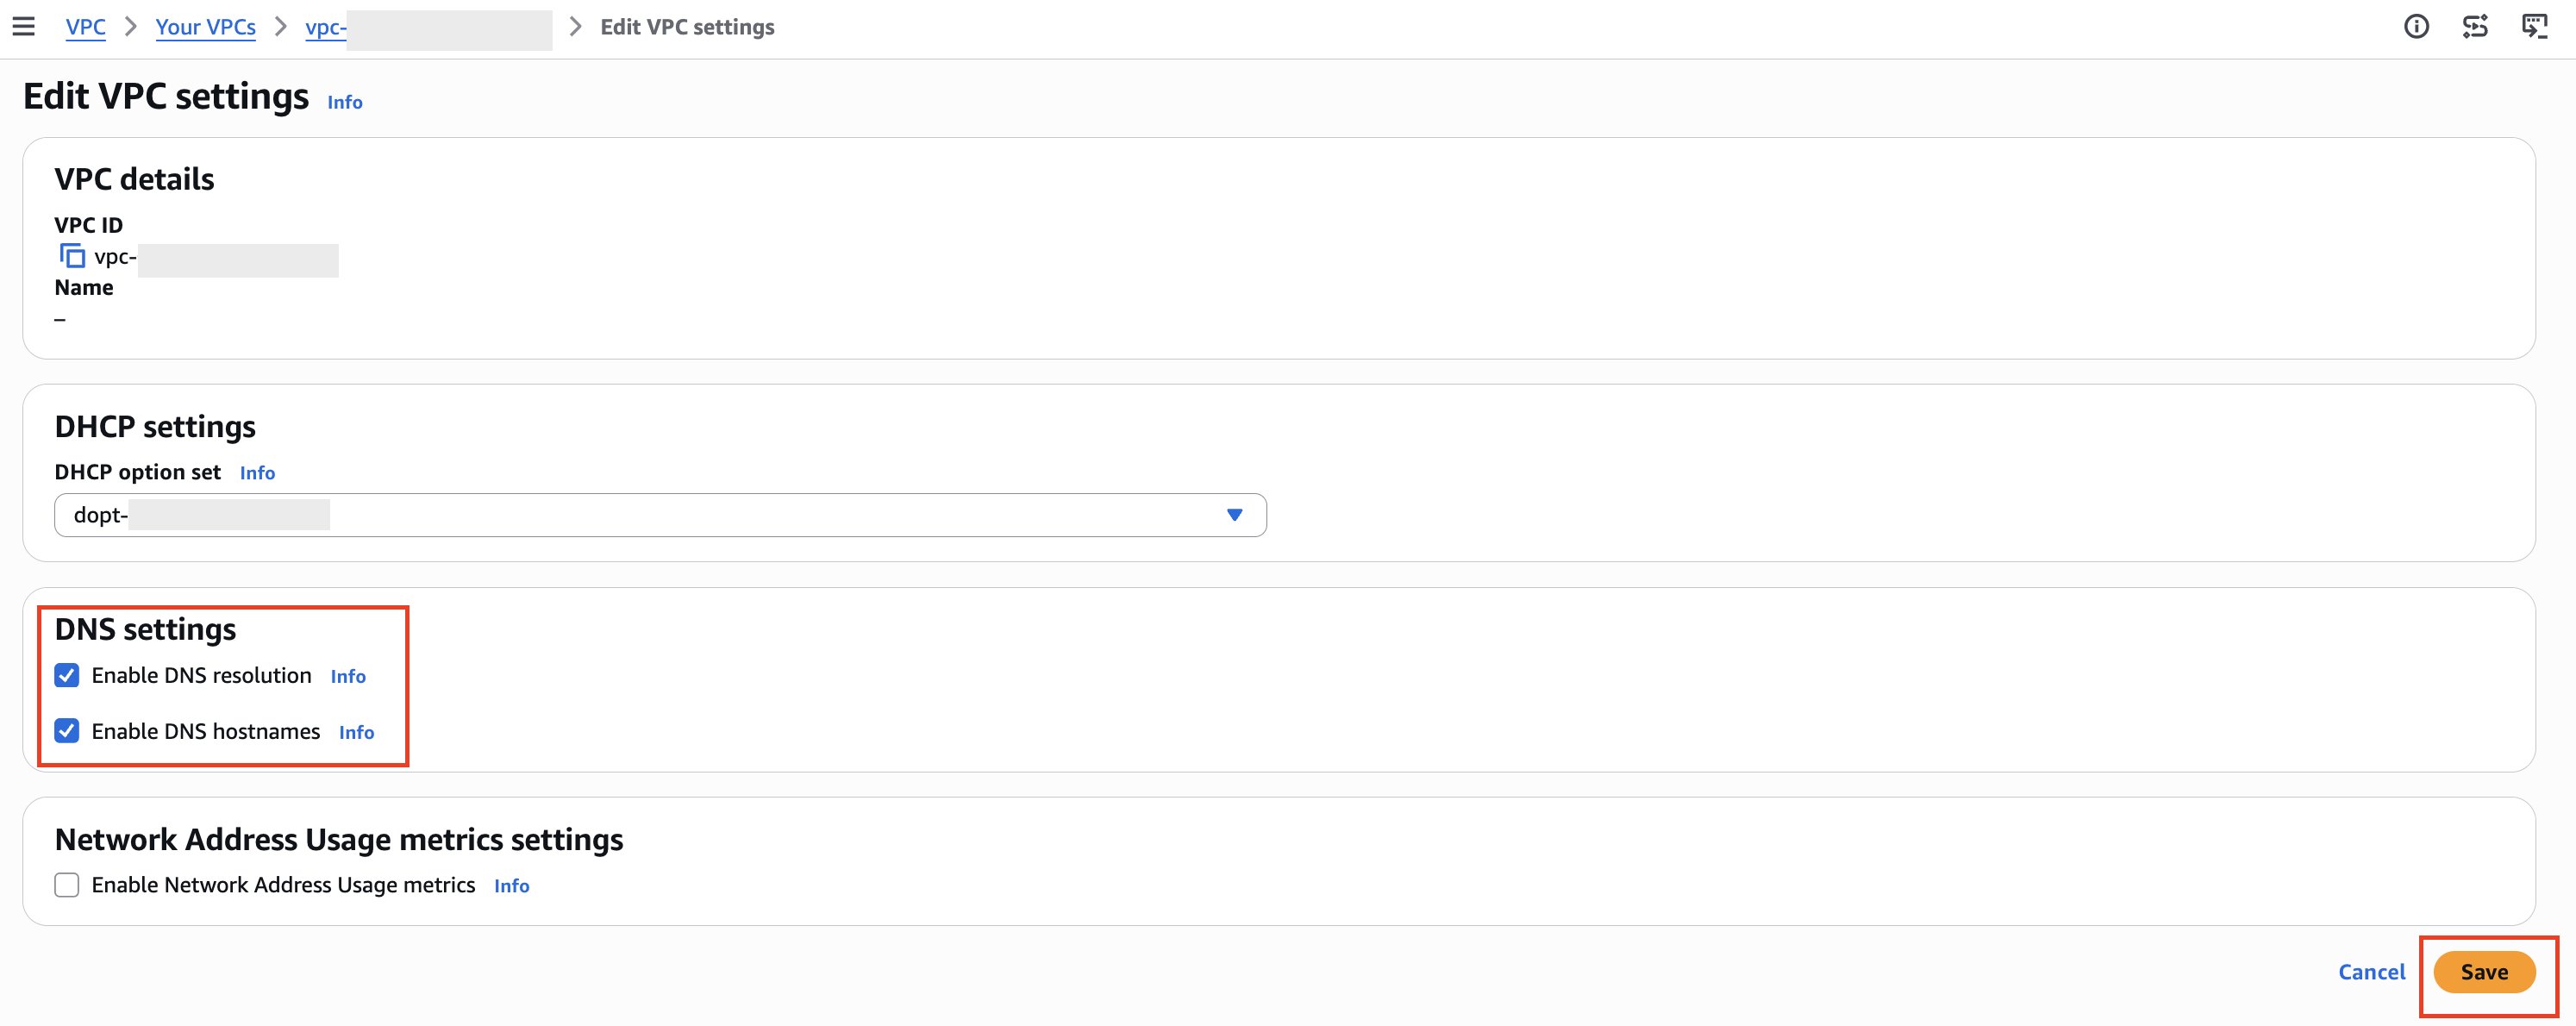
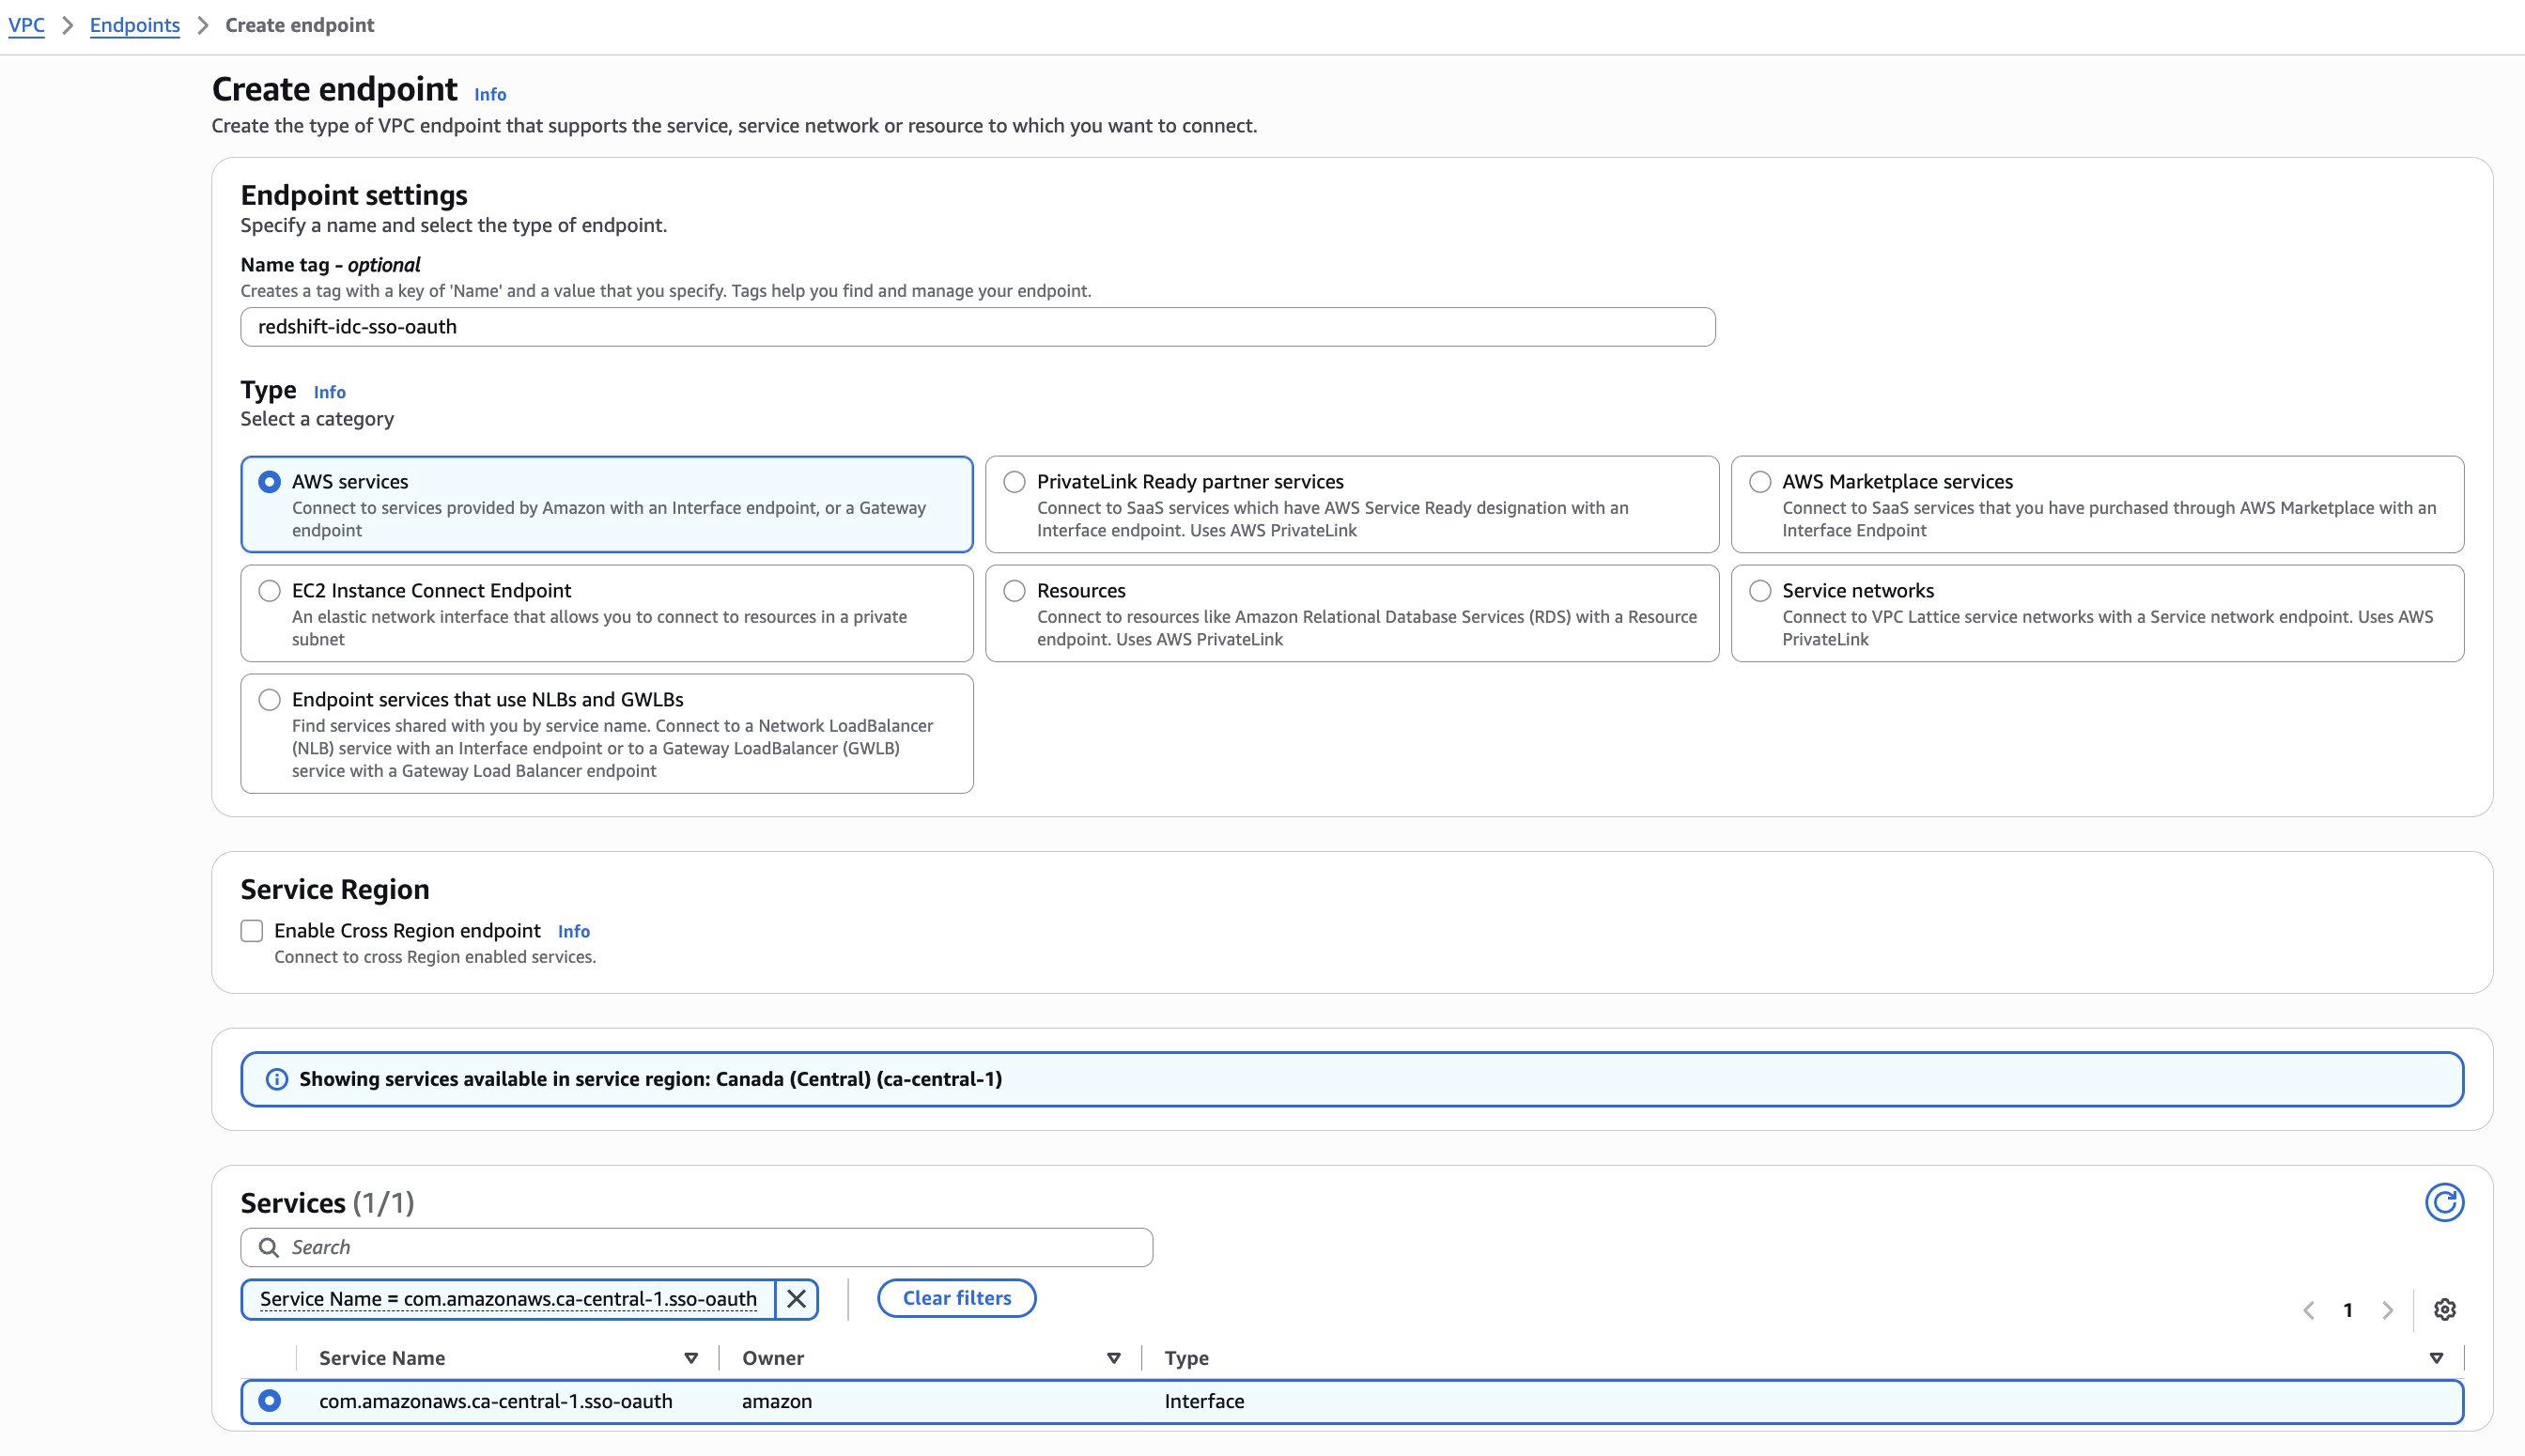
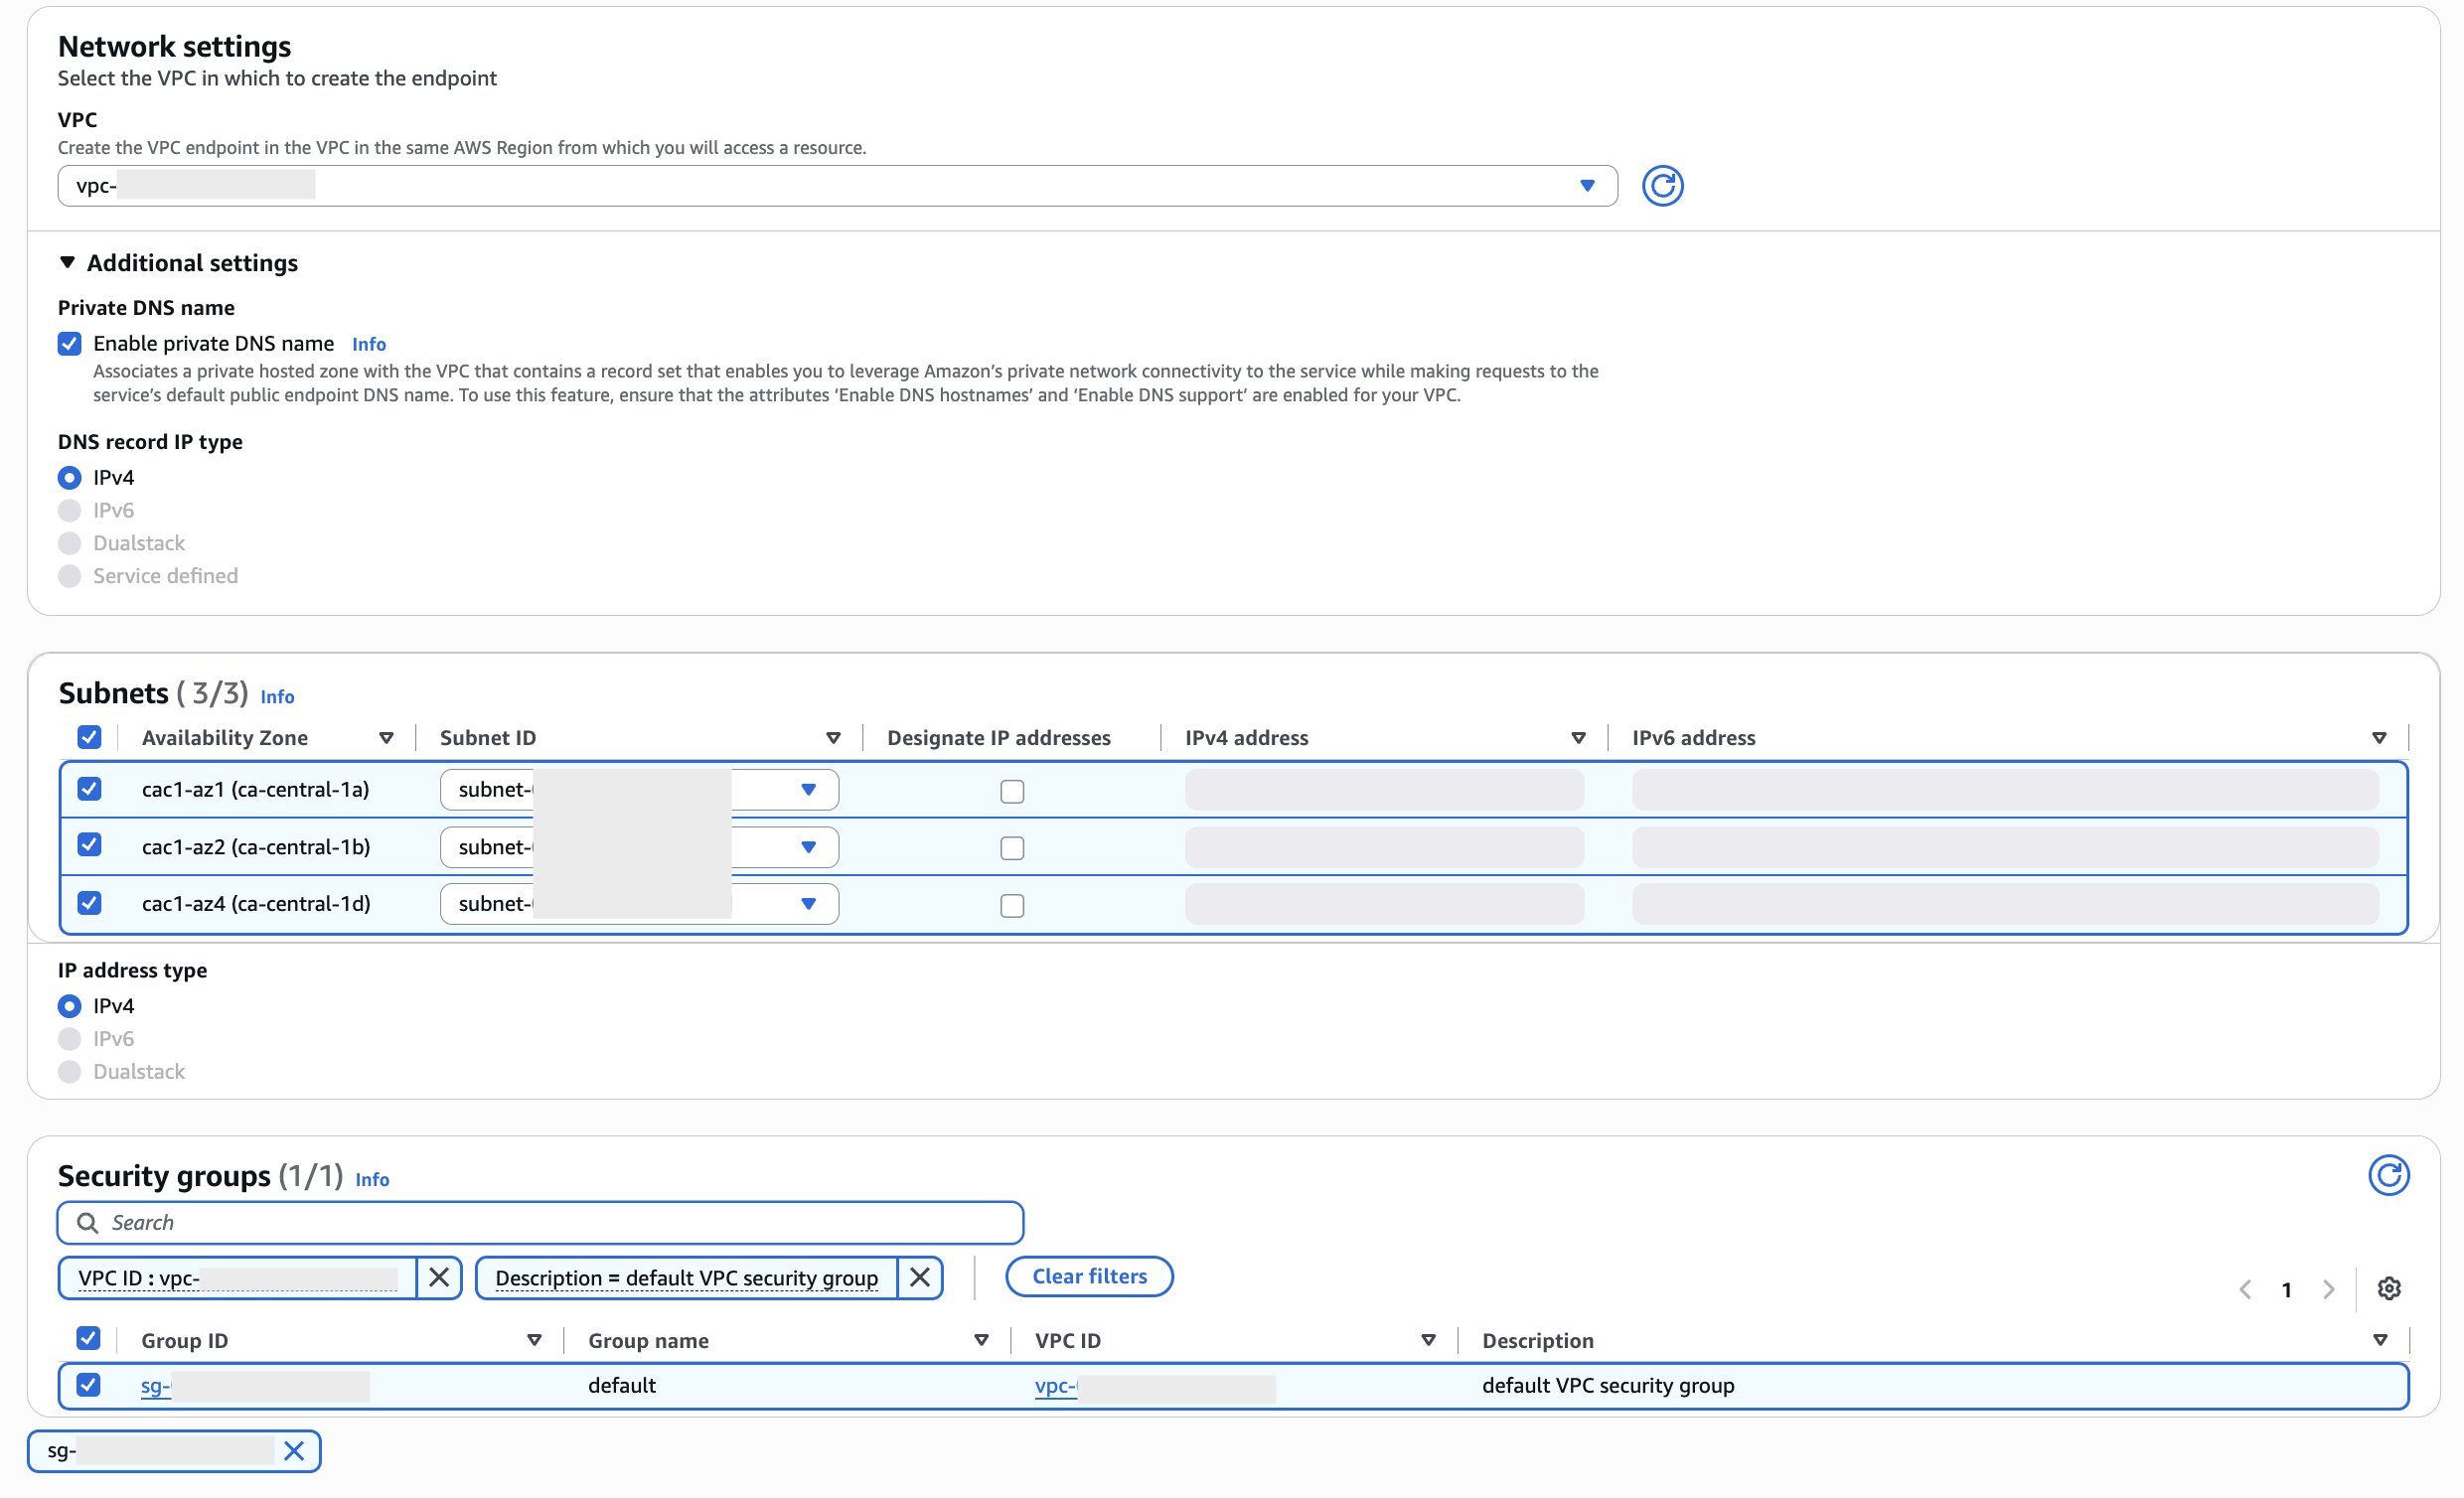
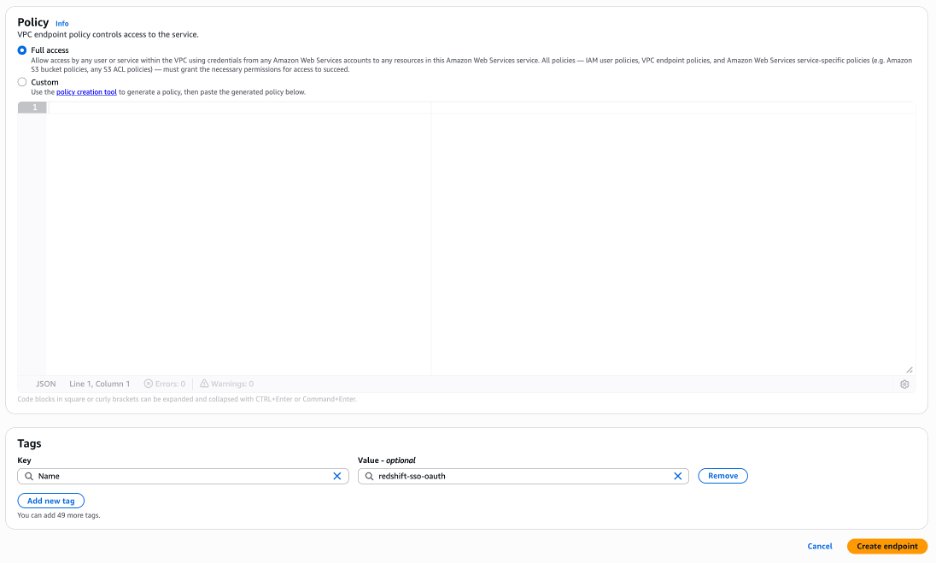
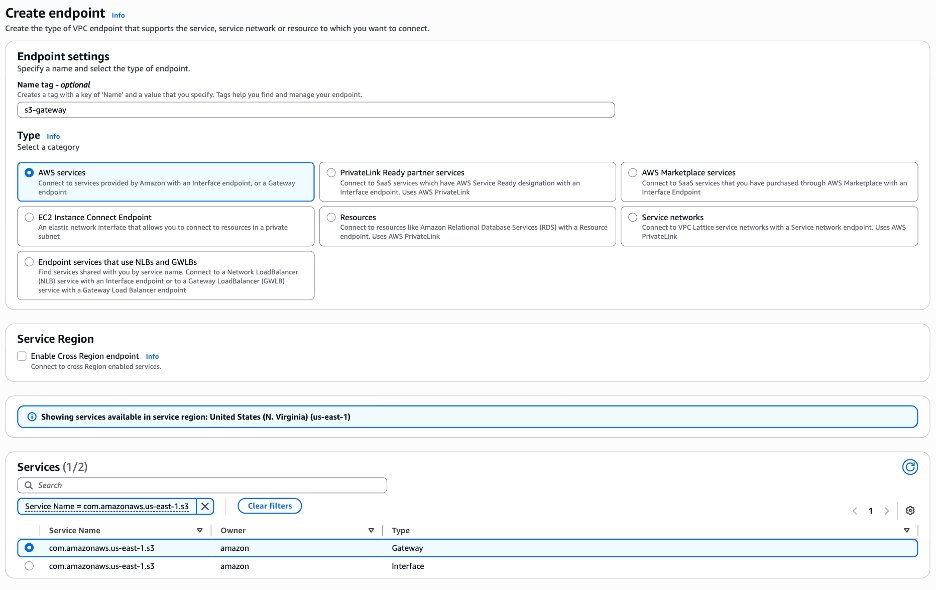
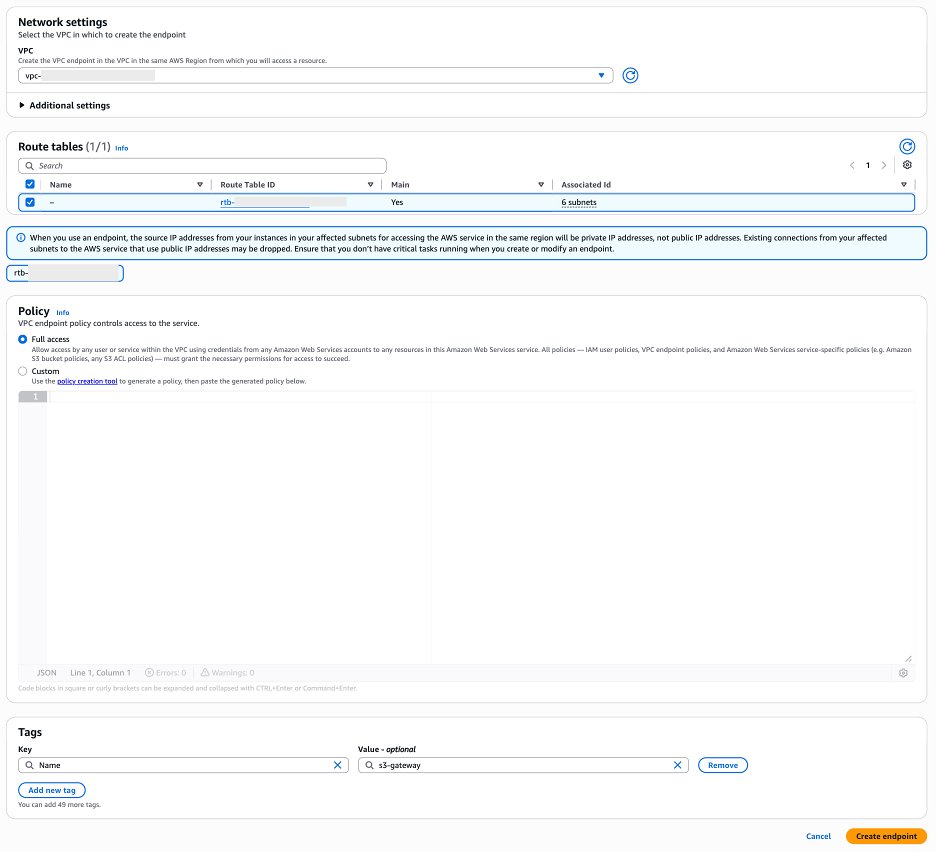
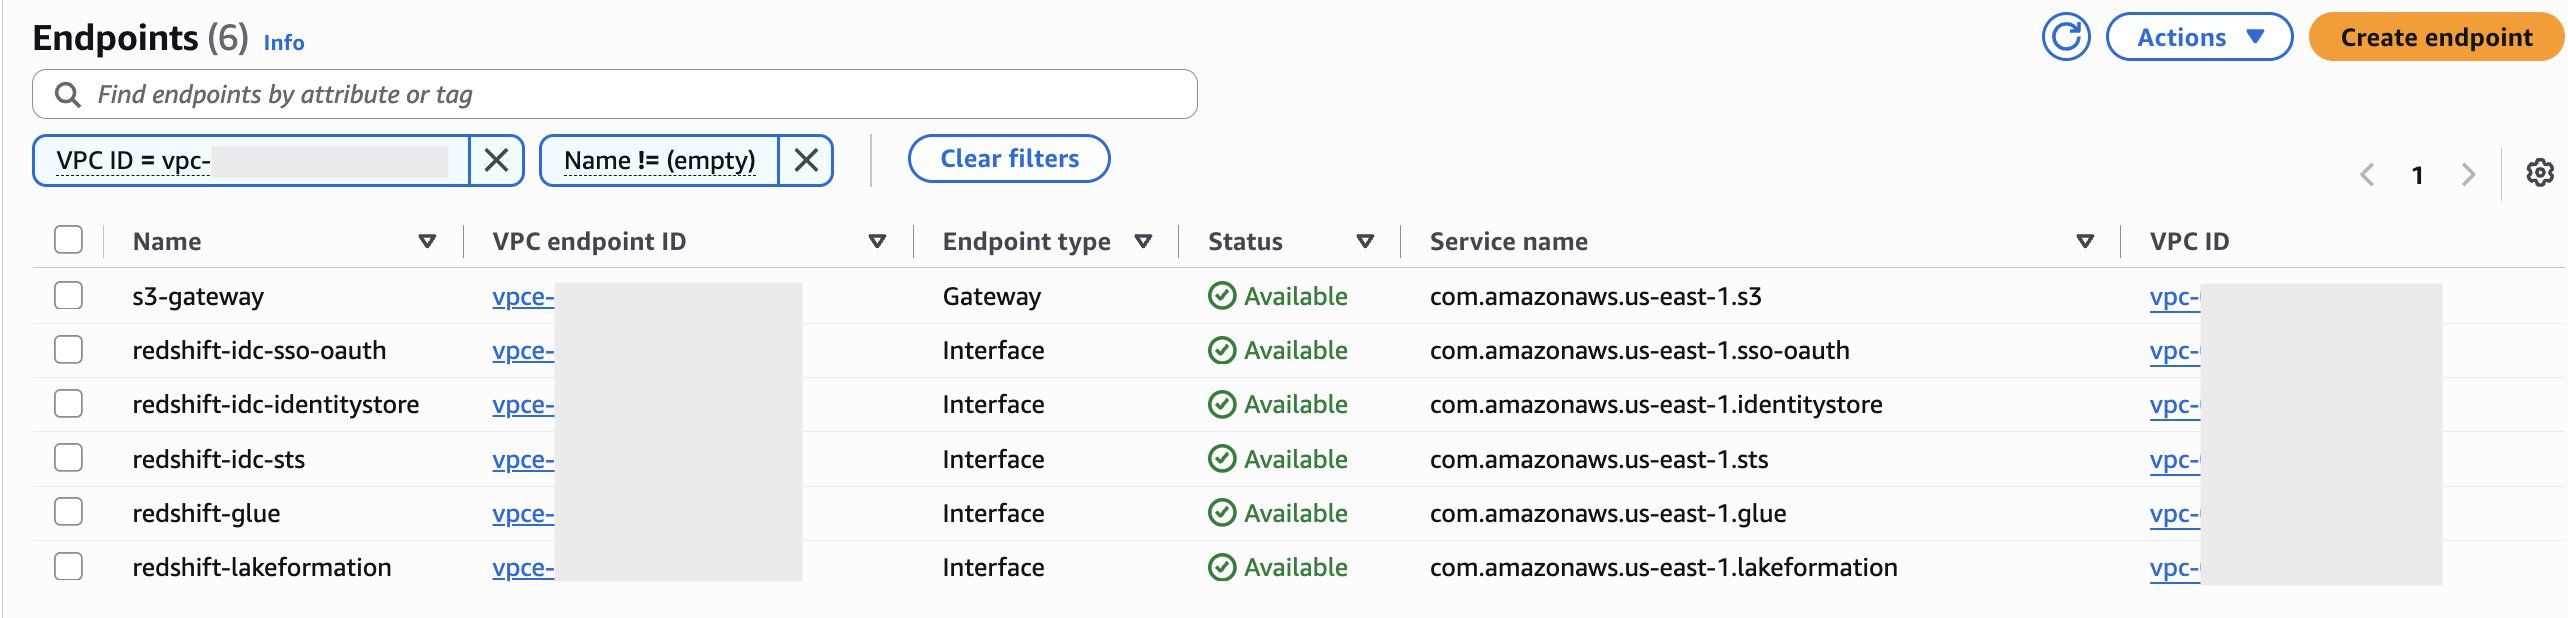
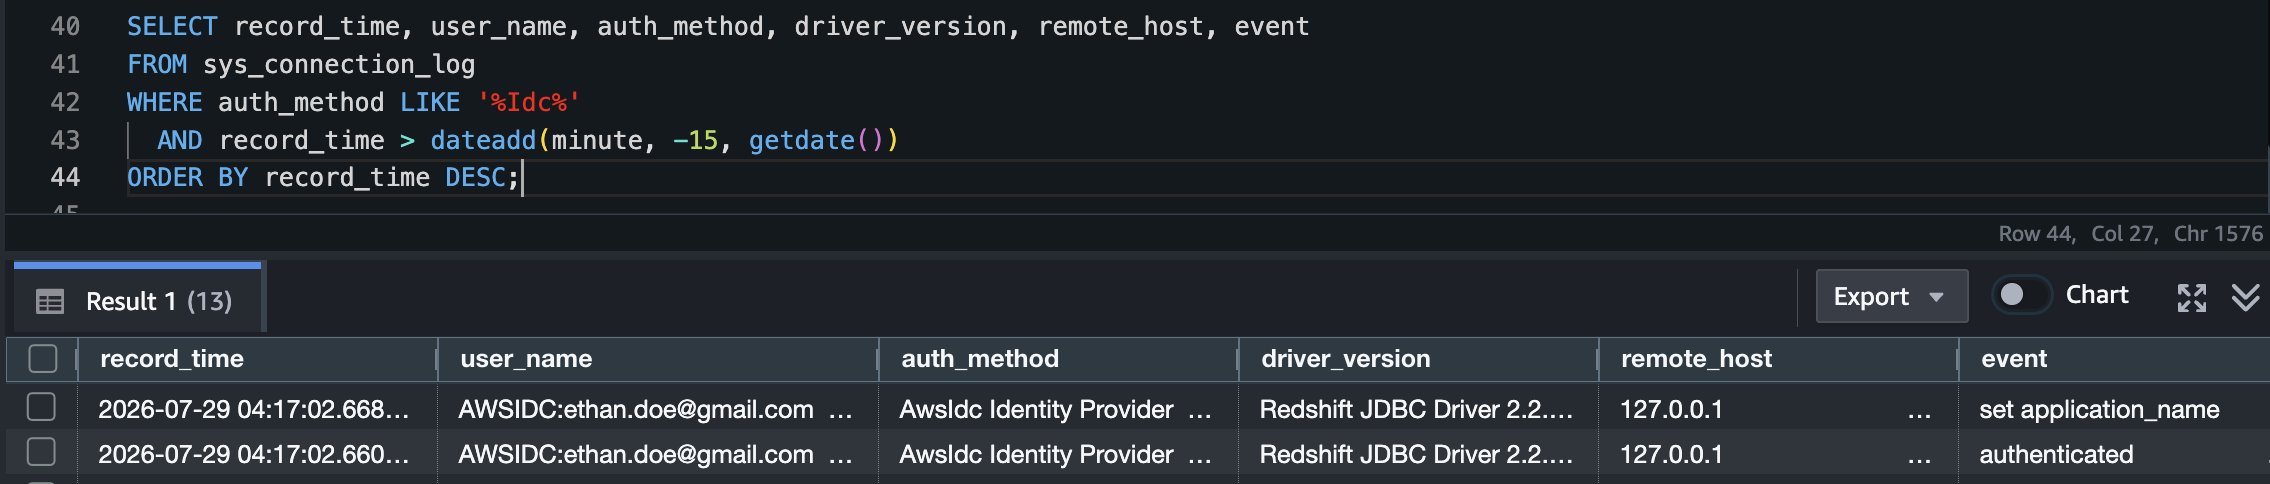
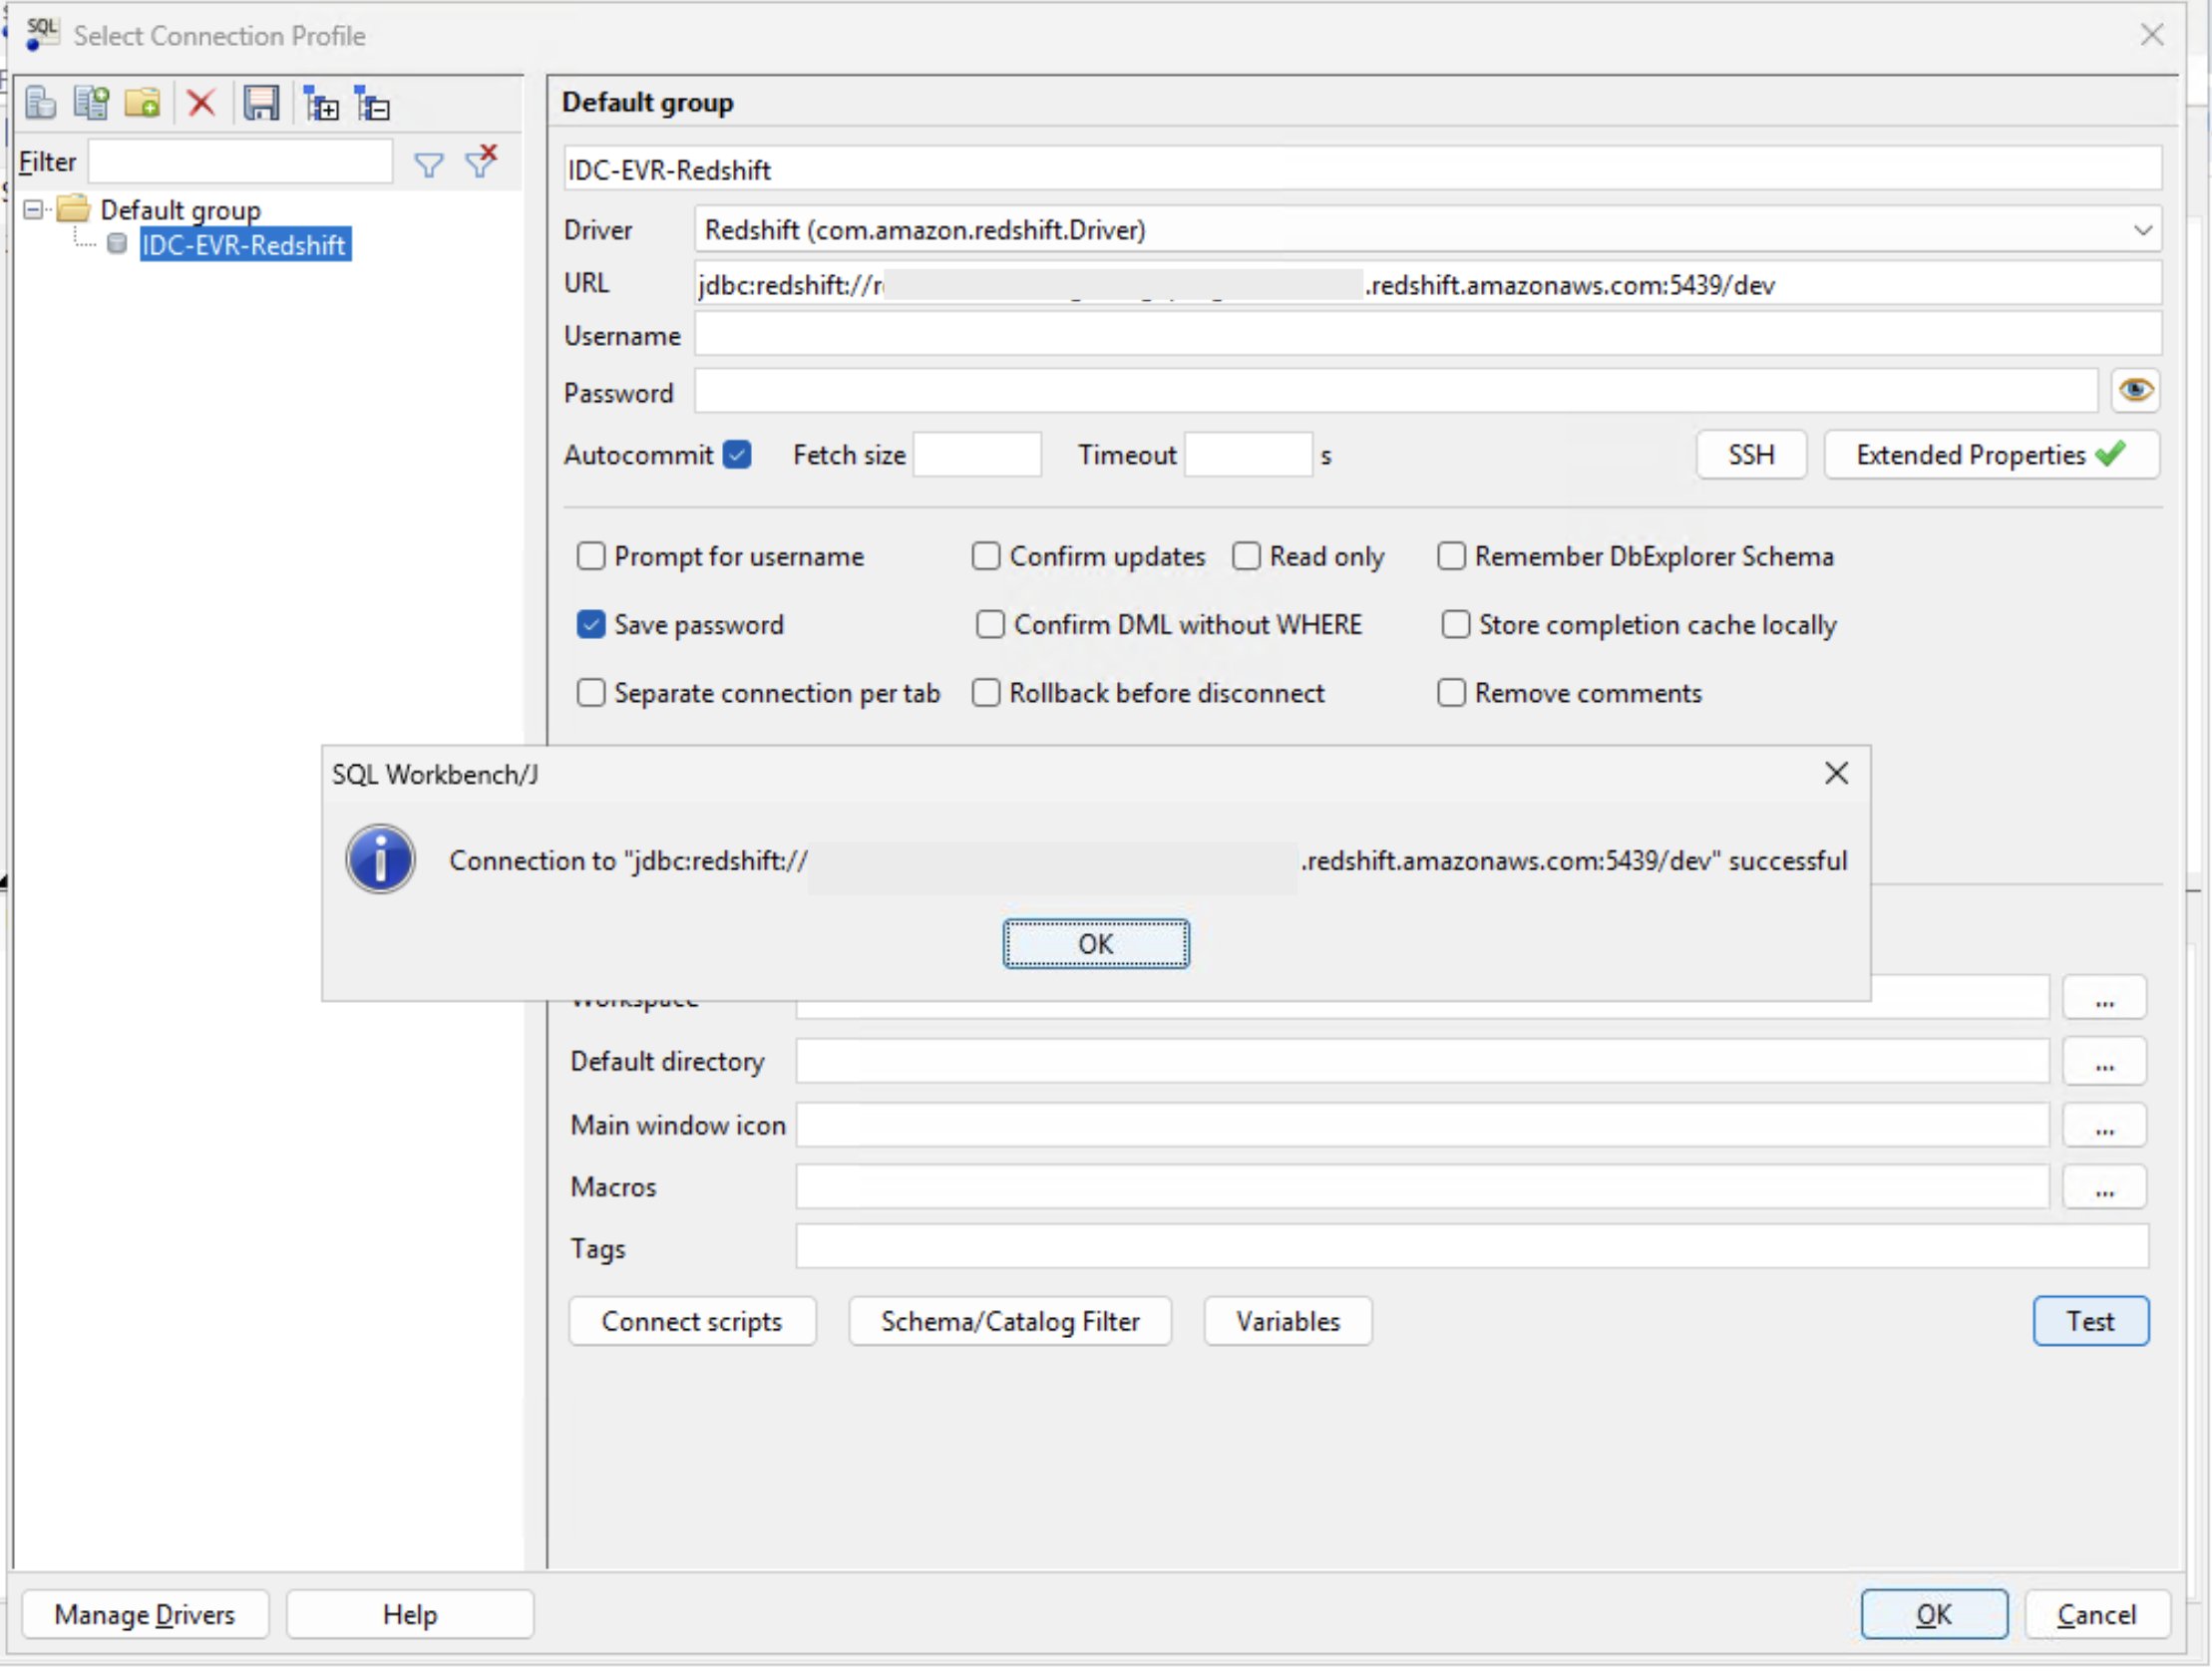
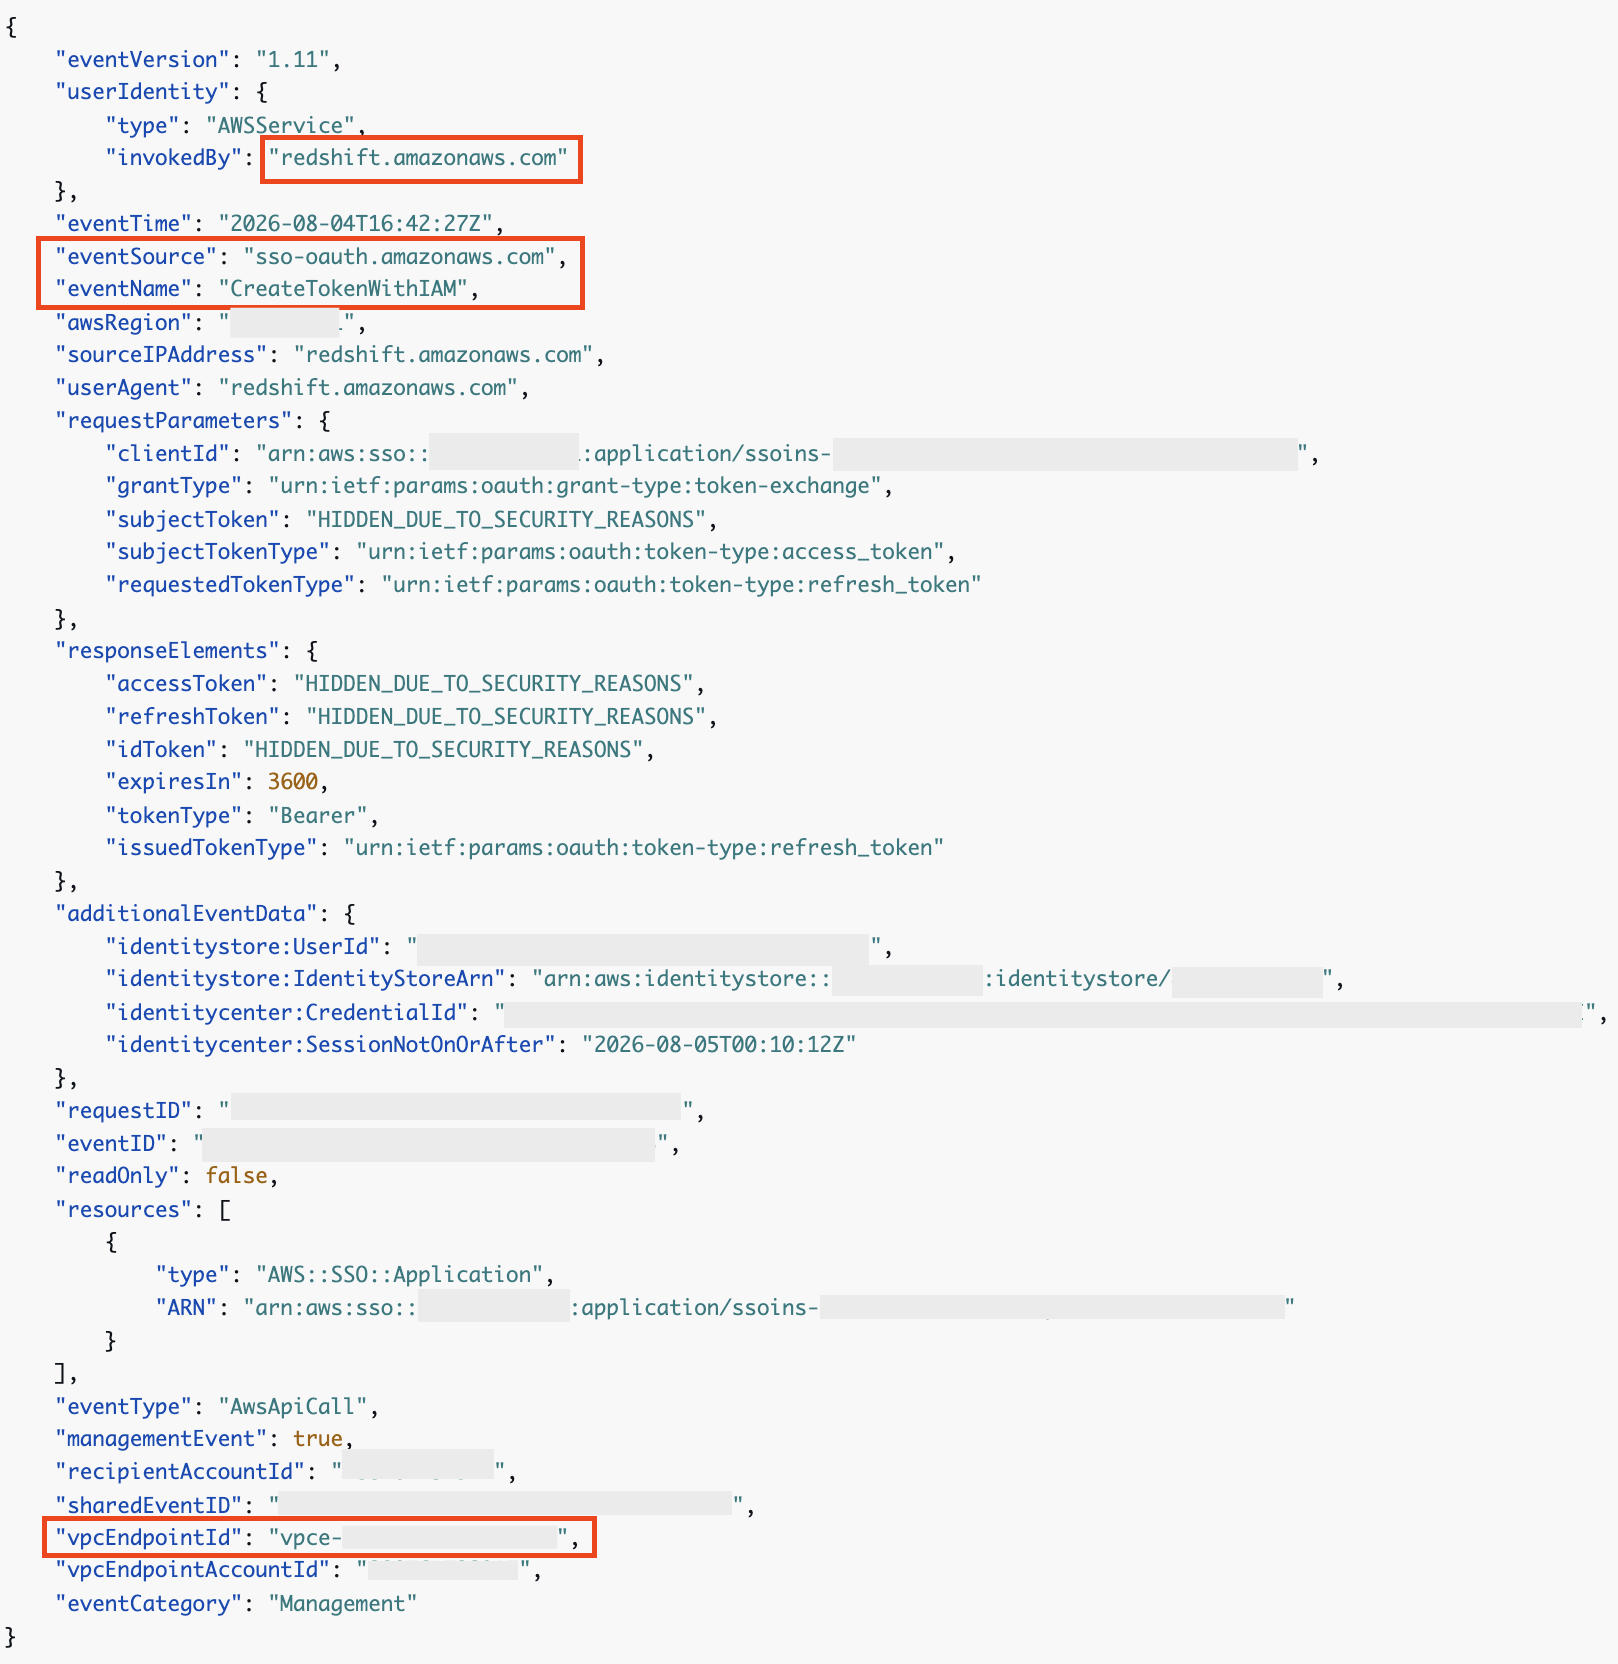
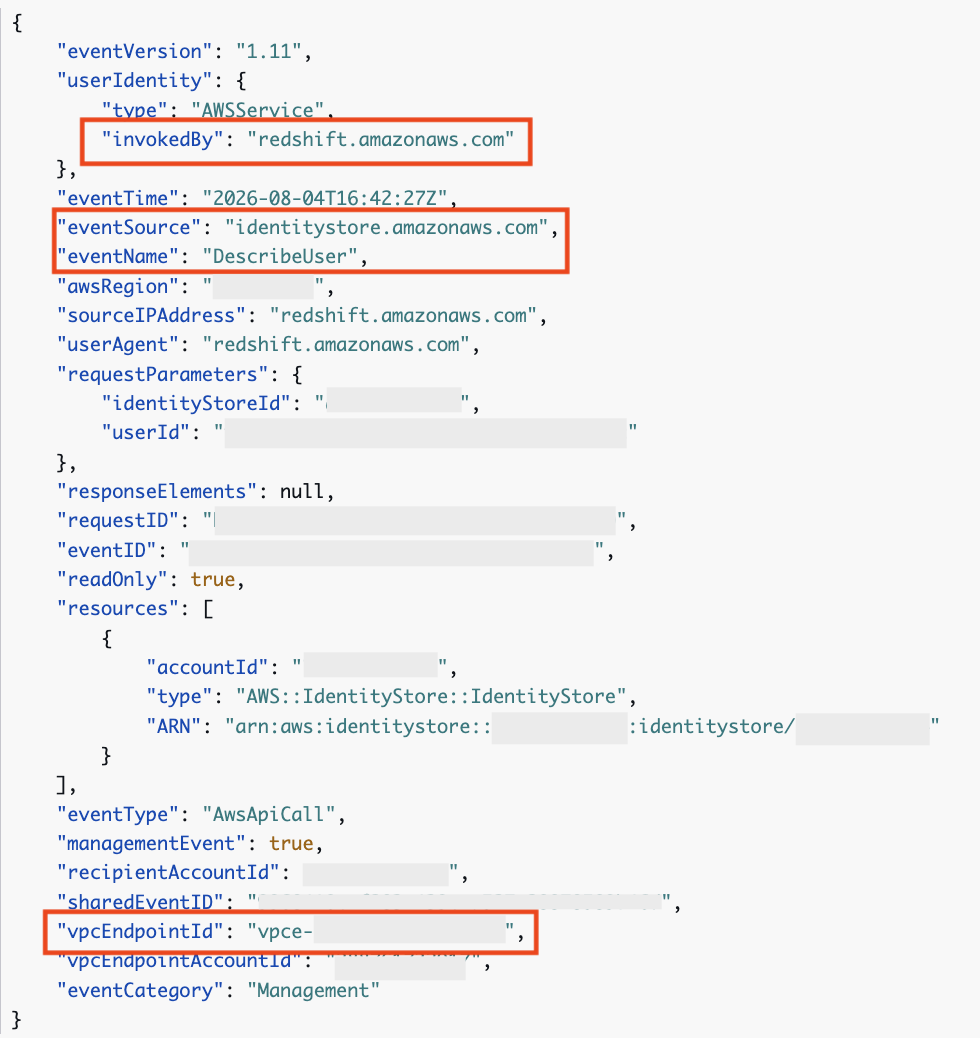
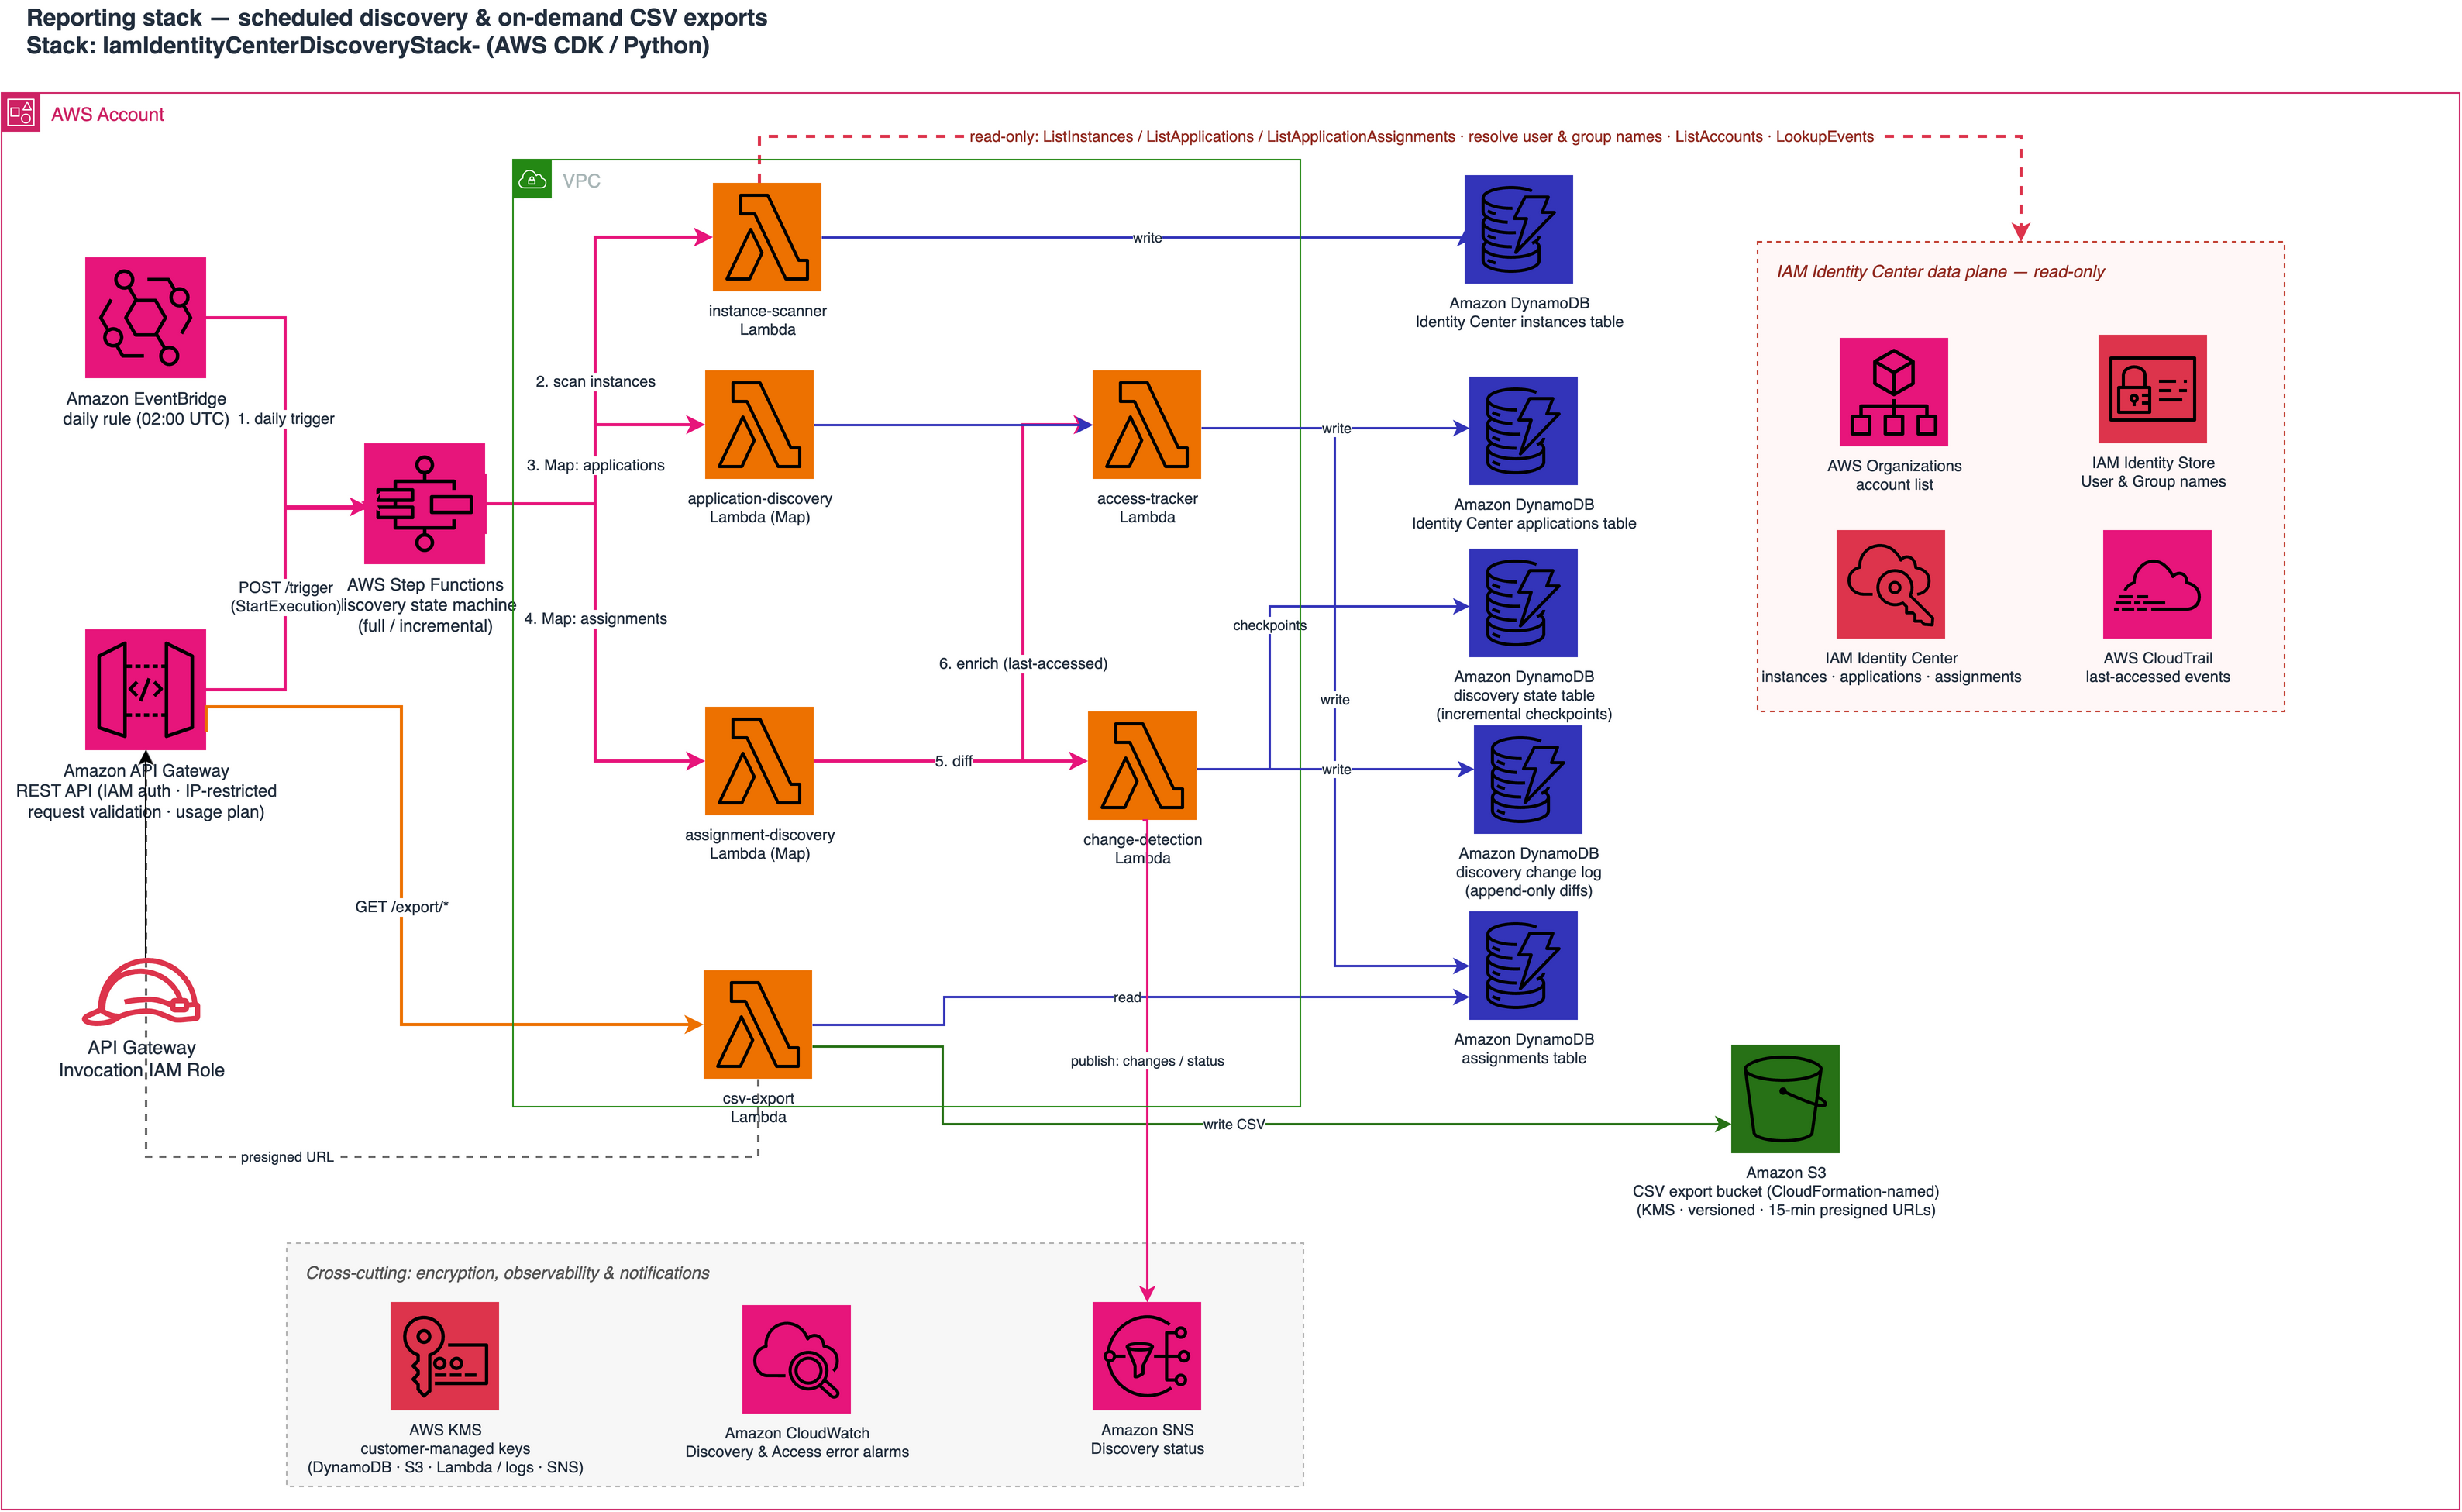
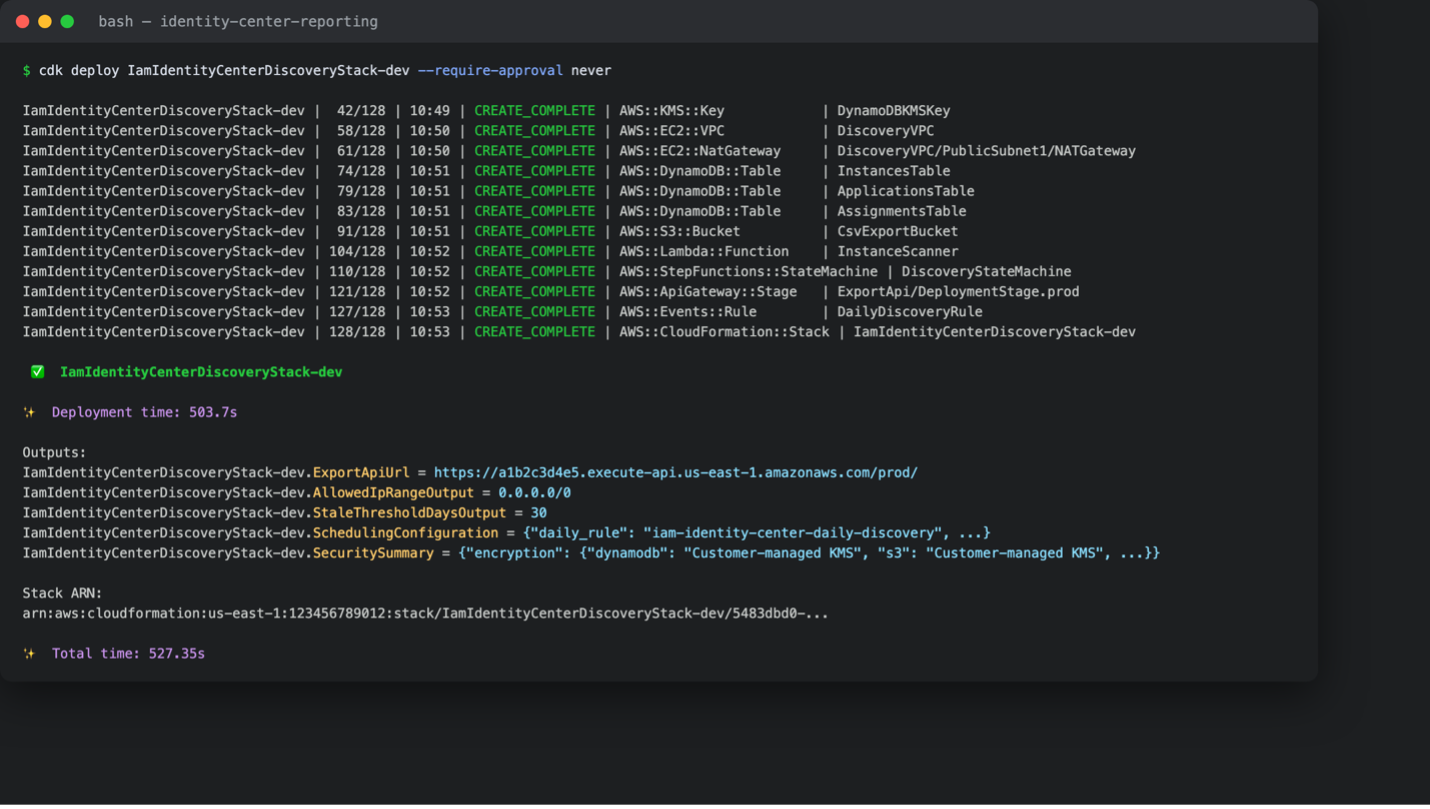
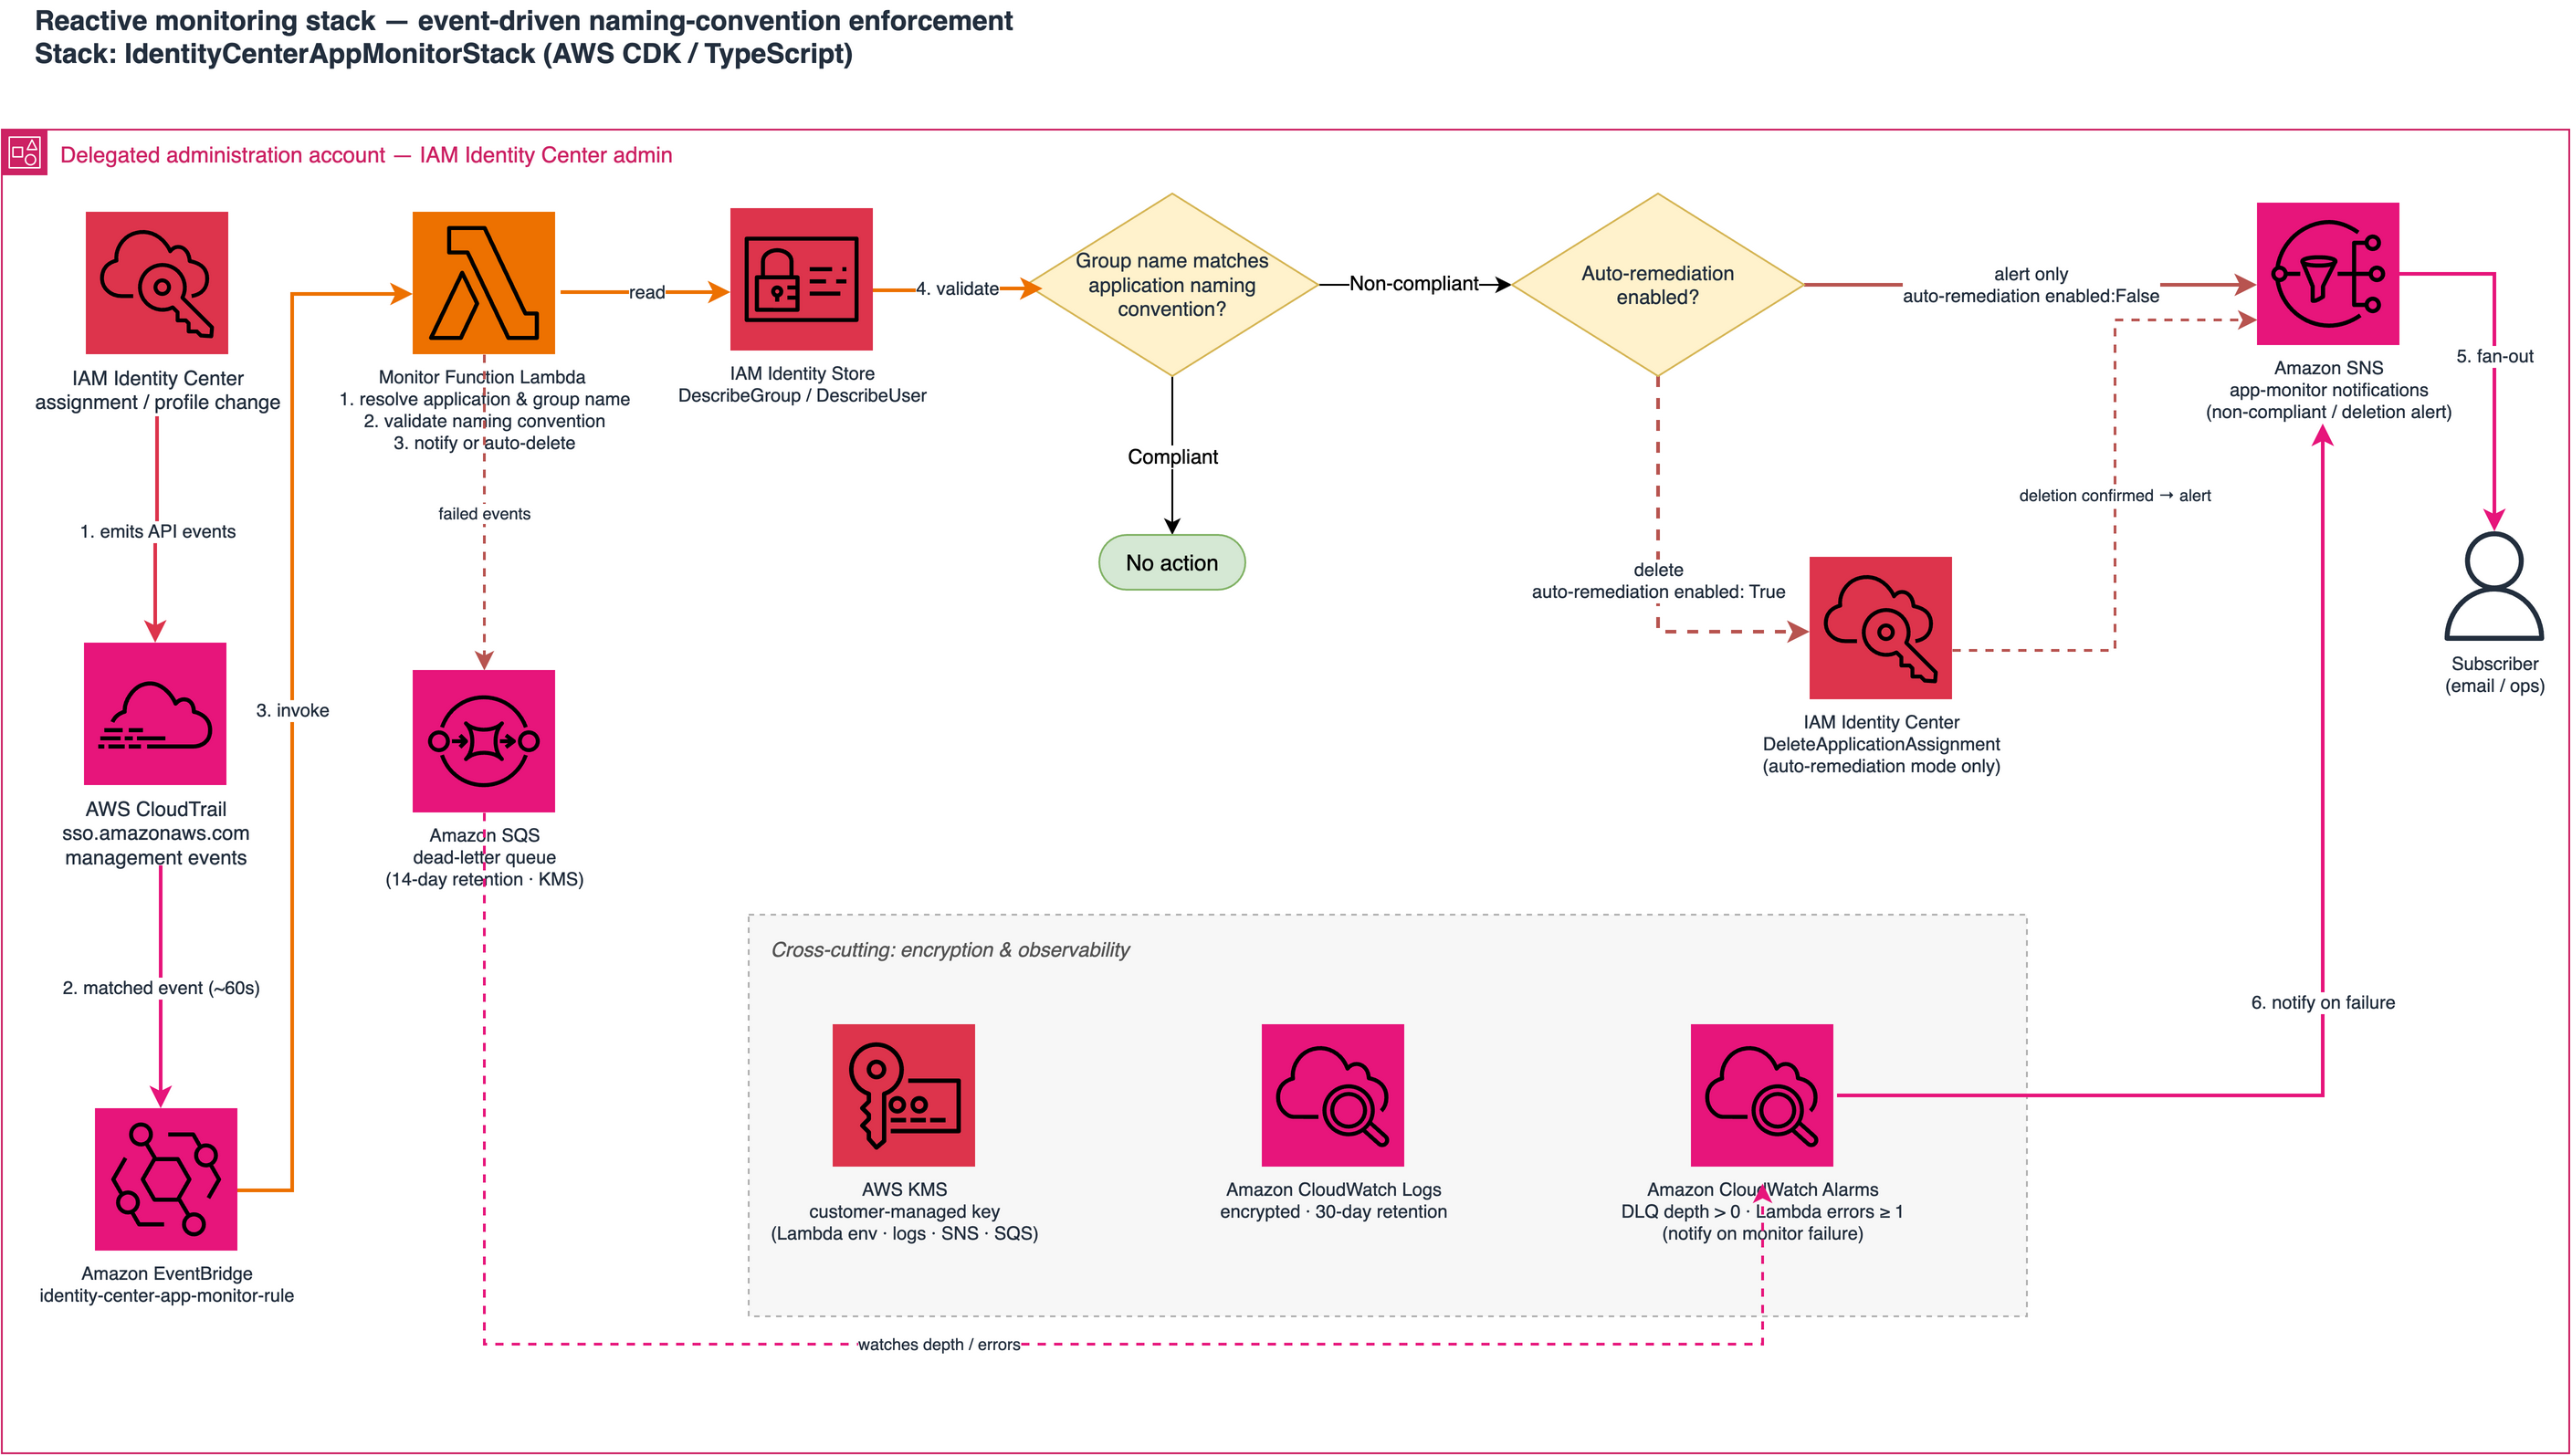
 Last week I had the joy of participating in Amazon’s “Bring Your Kids to Work Day” with my 7 year old son. We commuted together into the New York City office, his first real rush hour train ride, and spent the day exploring how Amazon uses AI, machine learning, and robotics to deliver packages to customers all over the world. Watching his eyes light up as he saw robots navigating a fulfillment center reminded me why so many of us got into technology in the first place. There’s nothing quite like seeing that sense of wonder when something complex clicks.
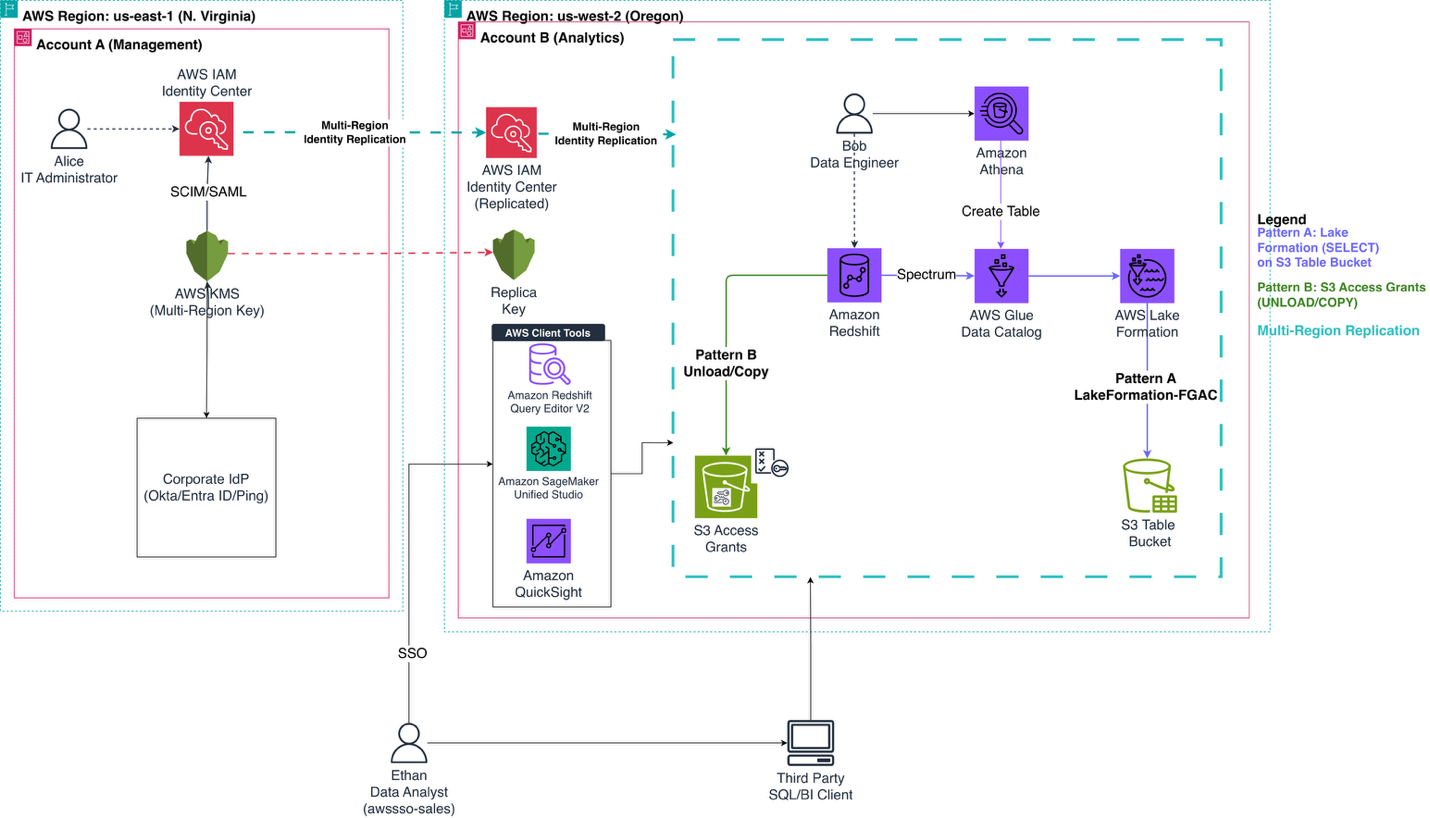
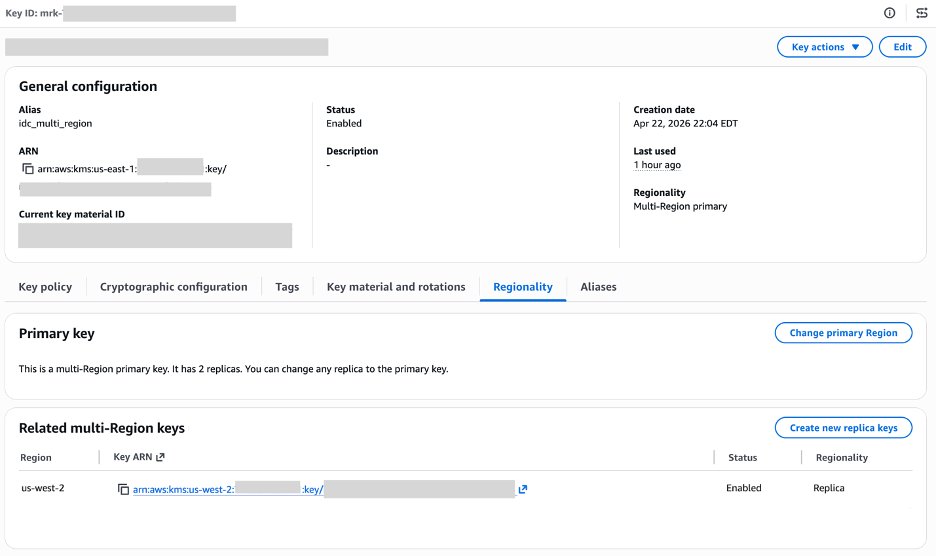
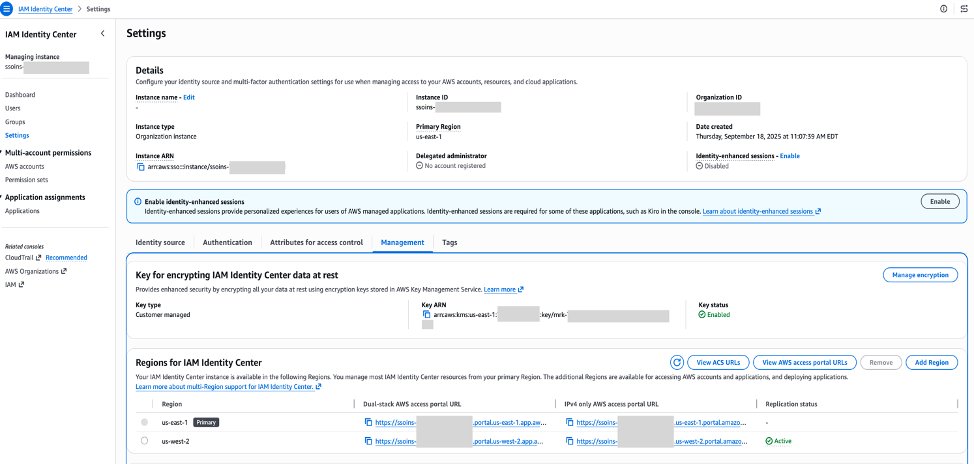
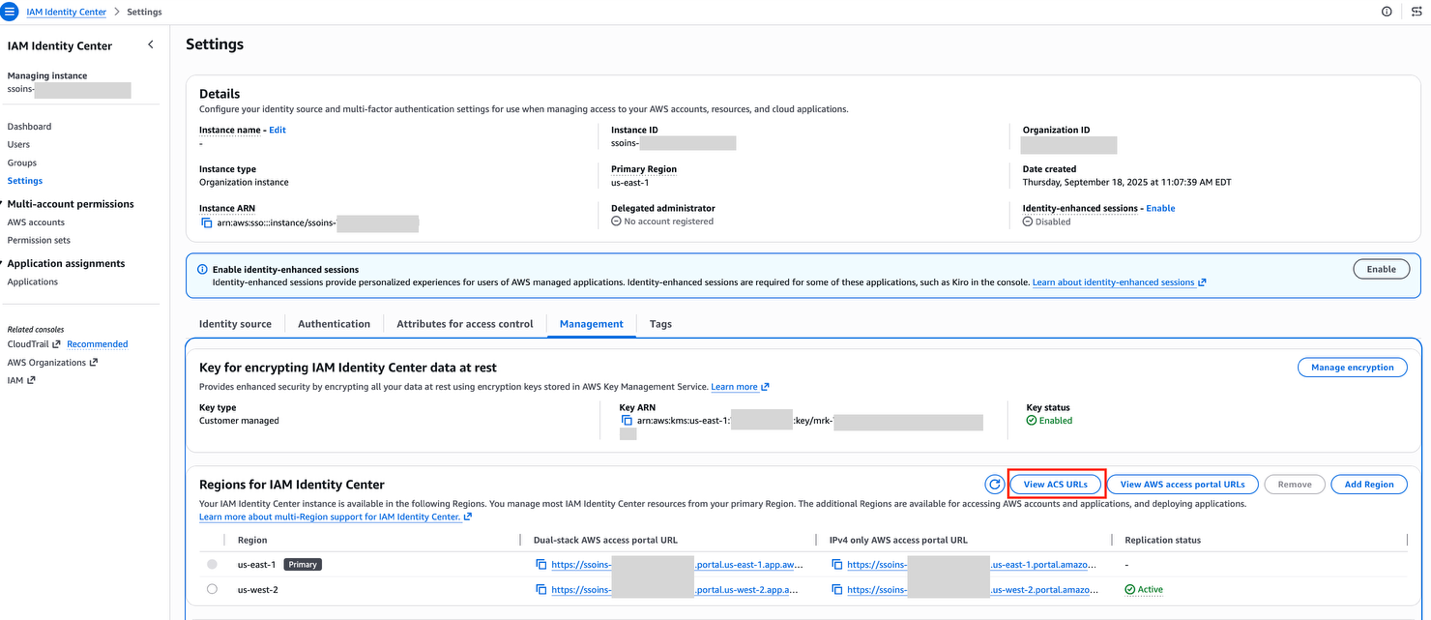
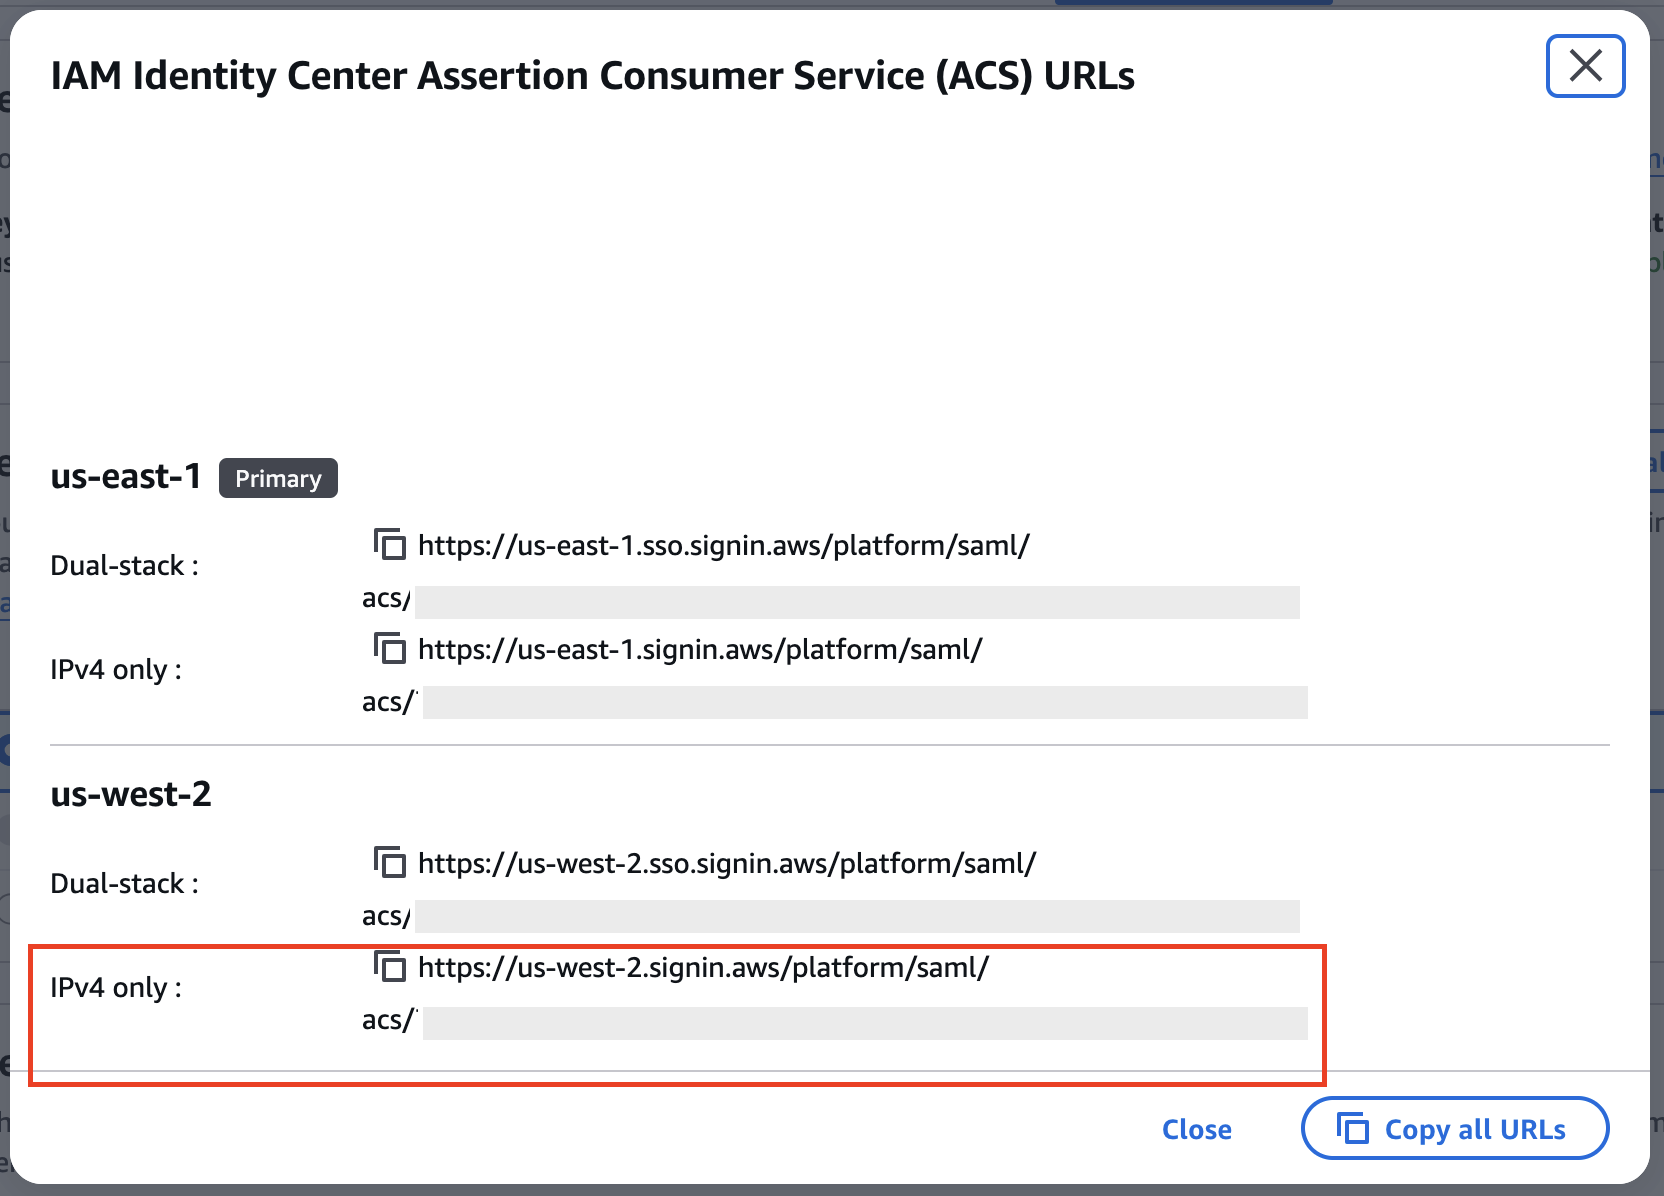
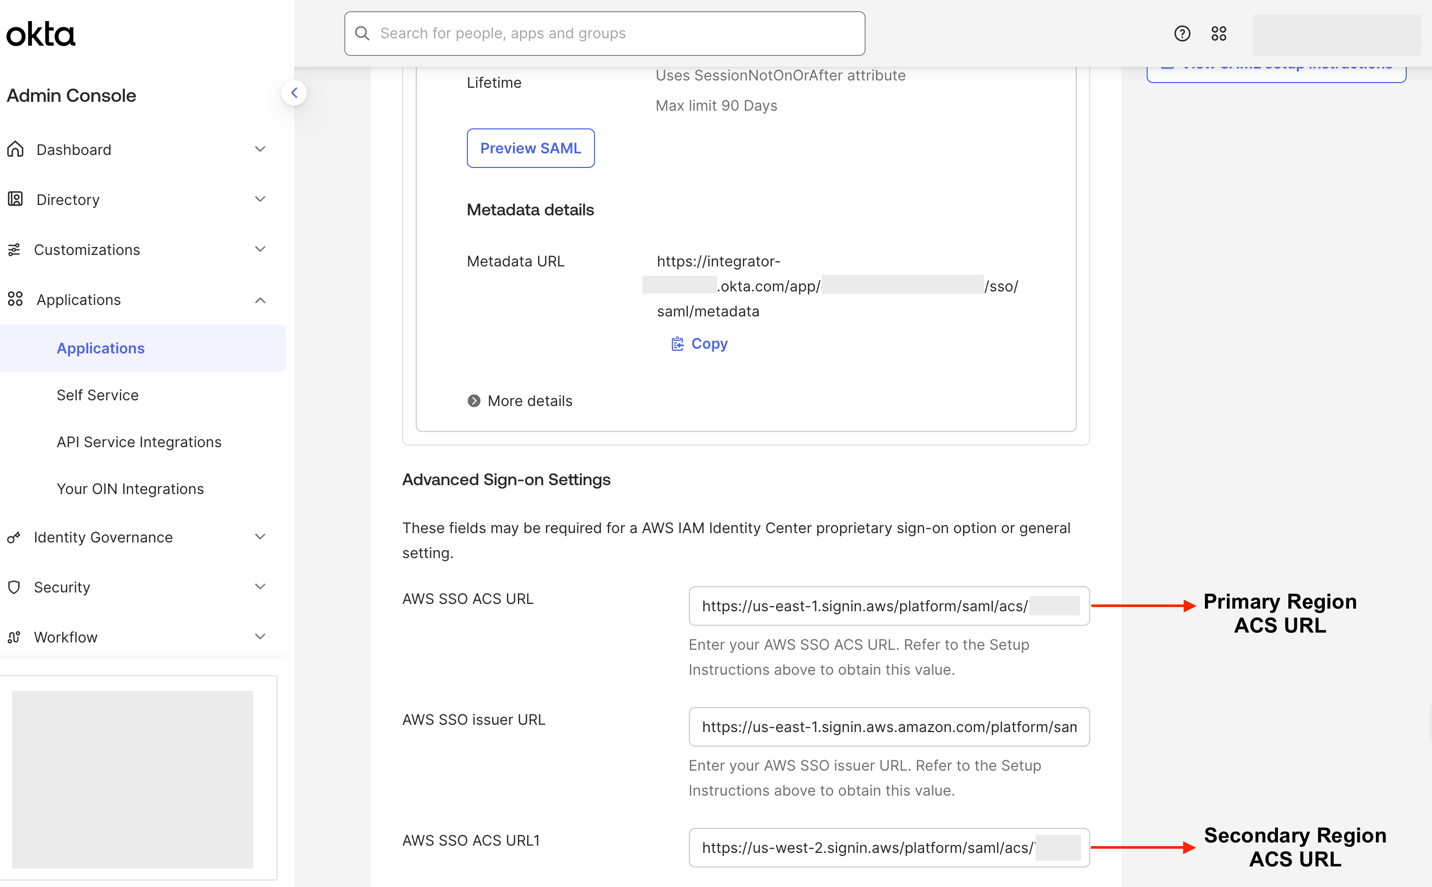
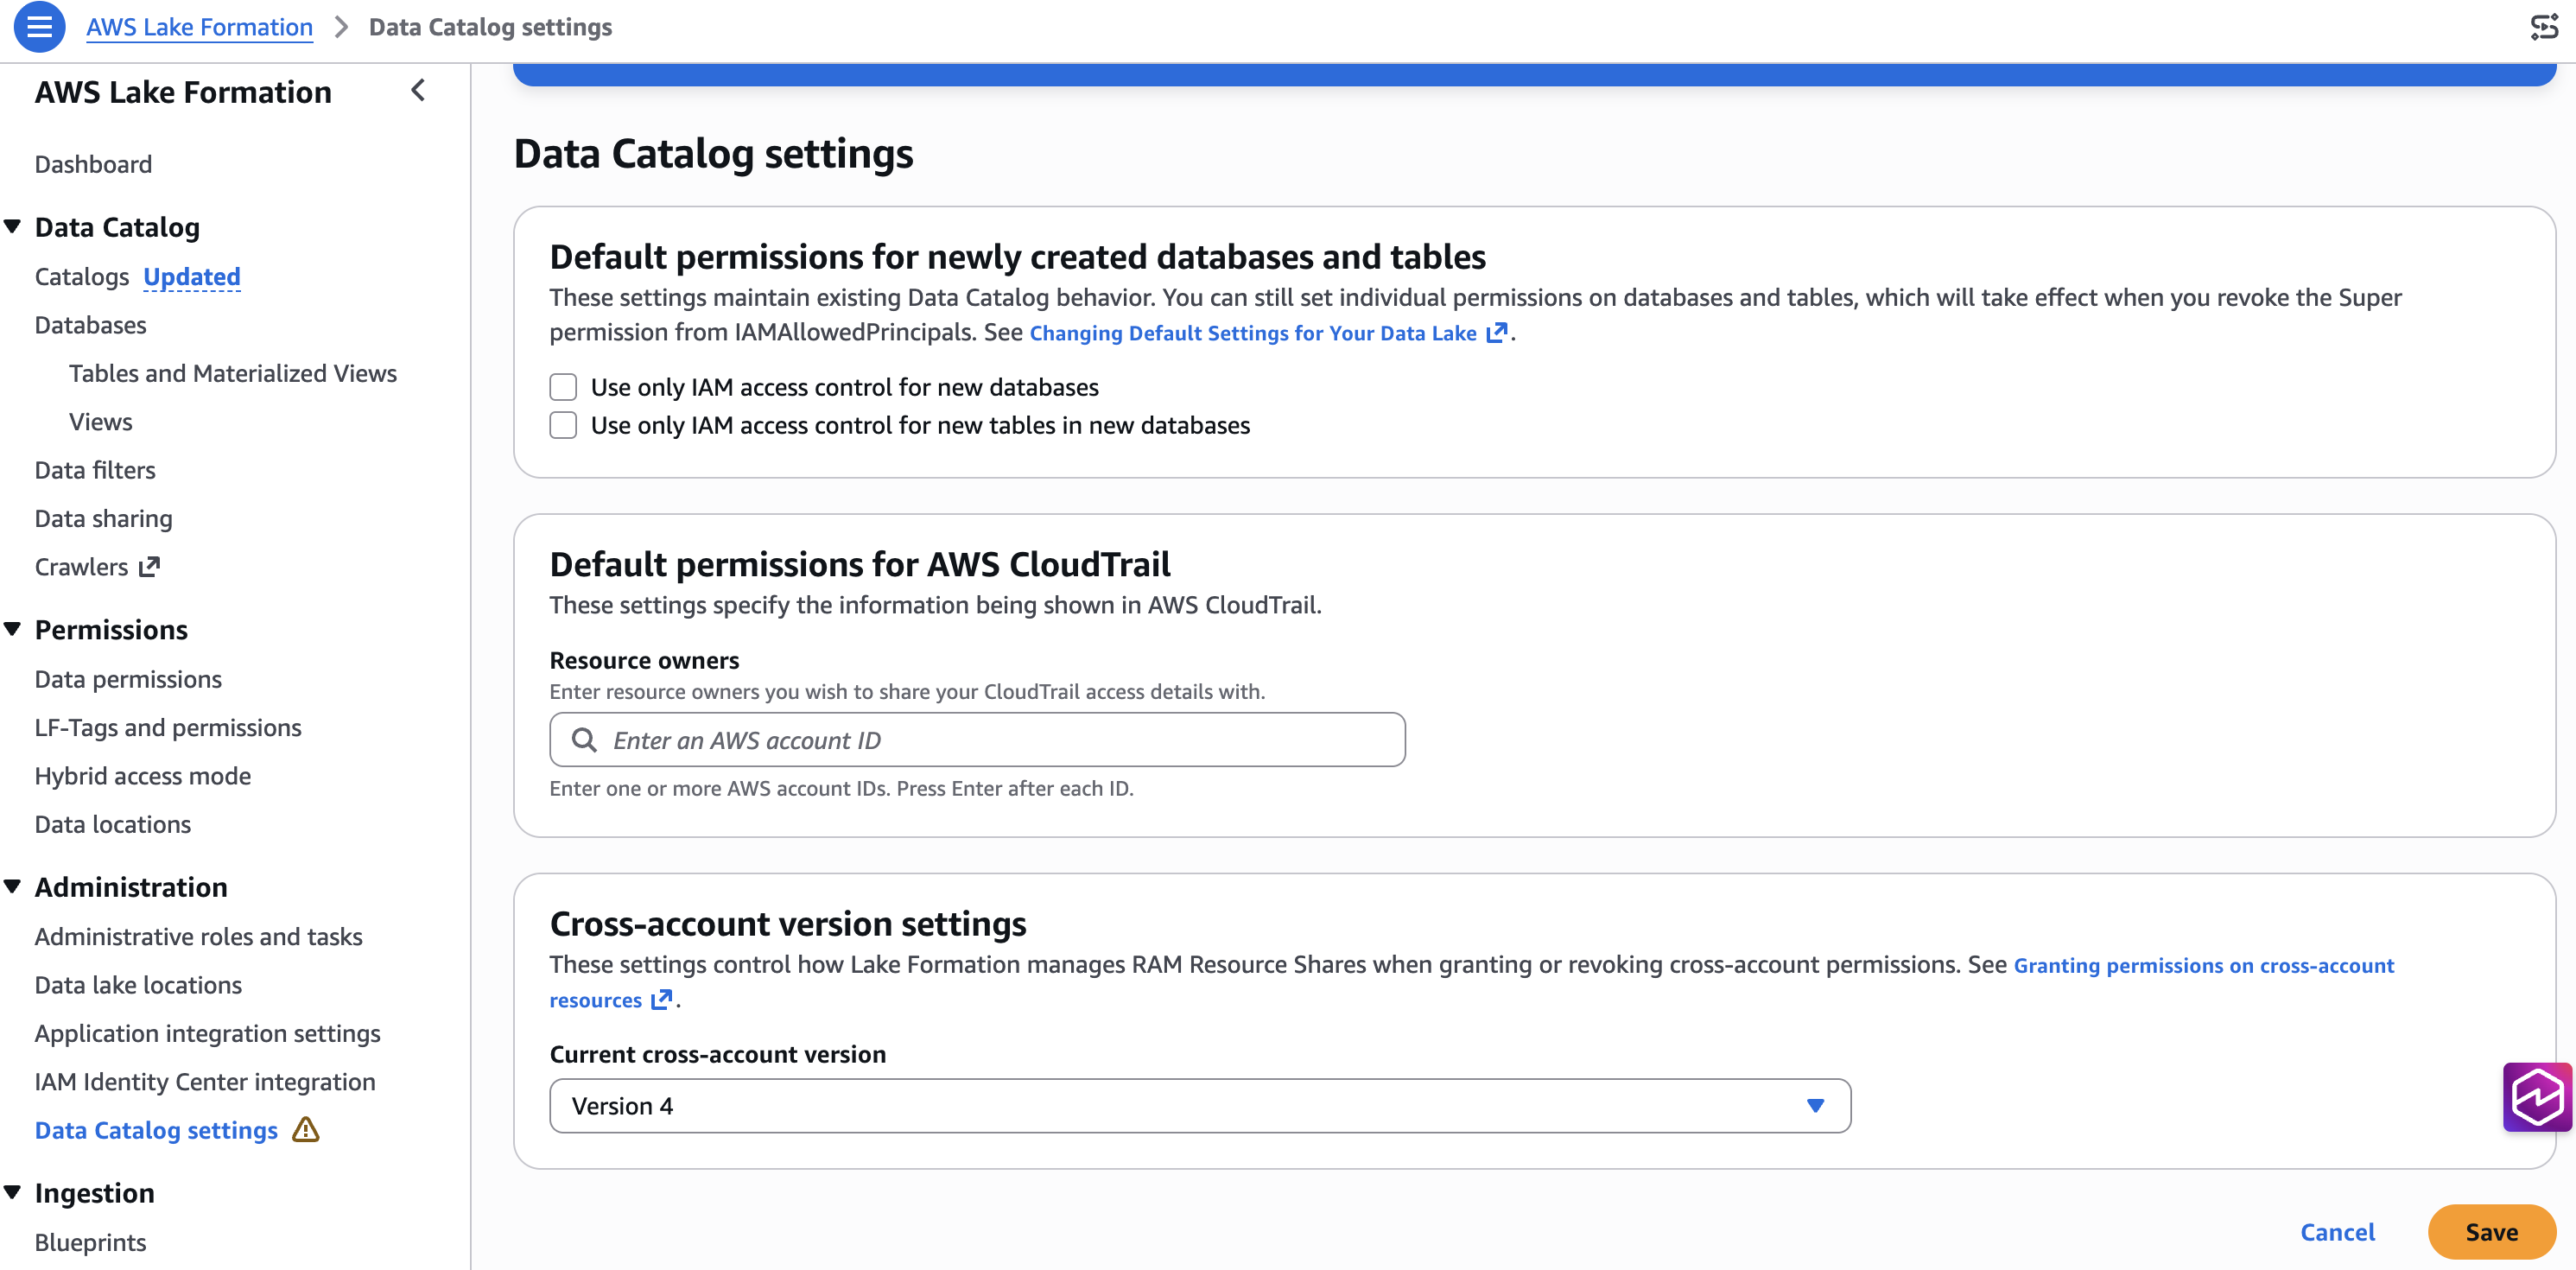
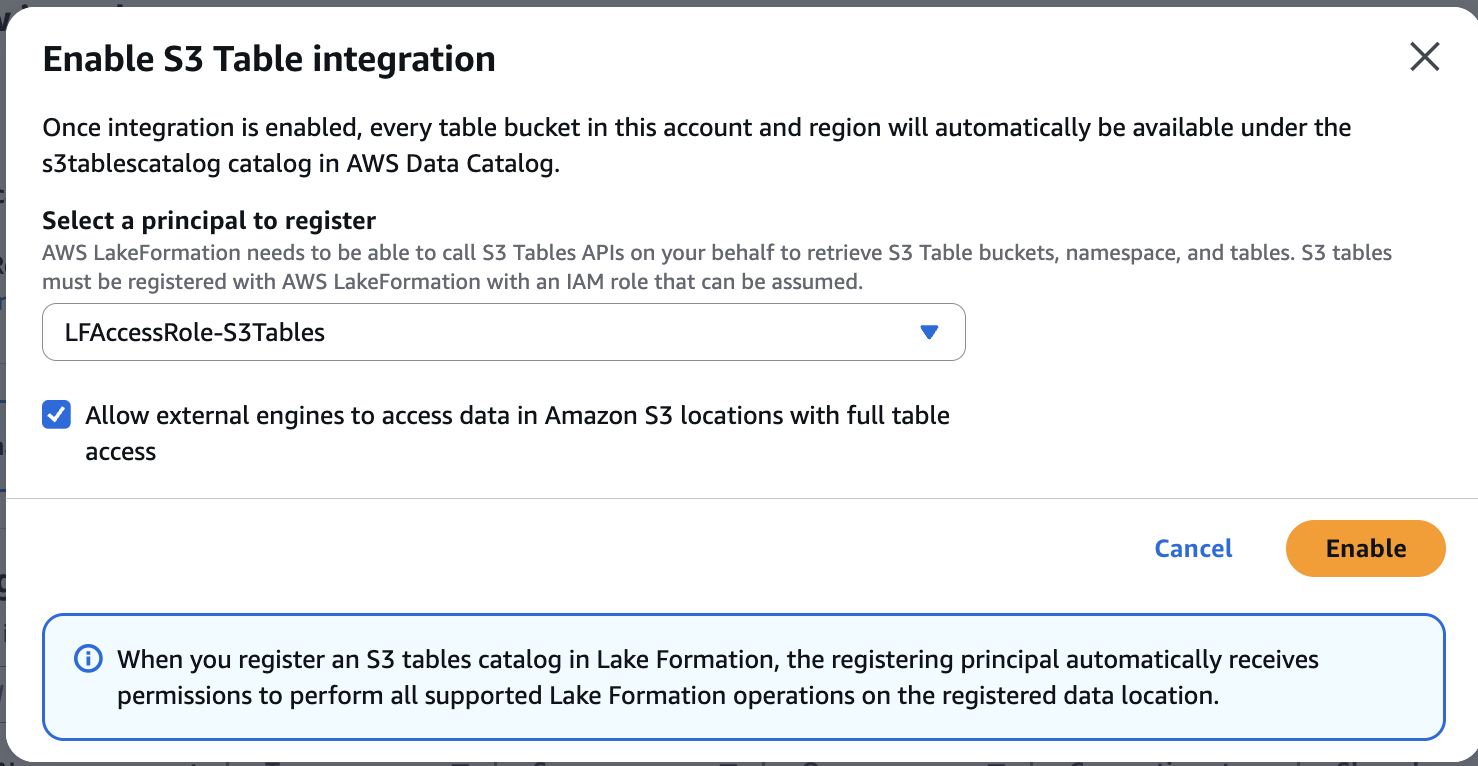
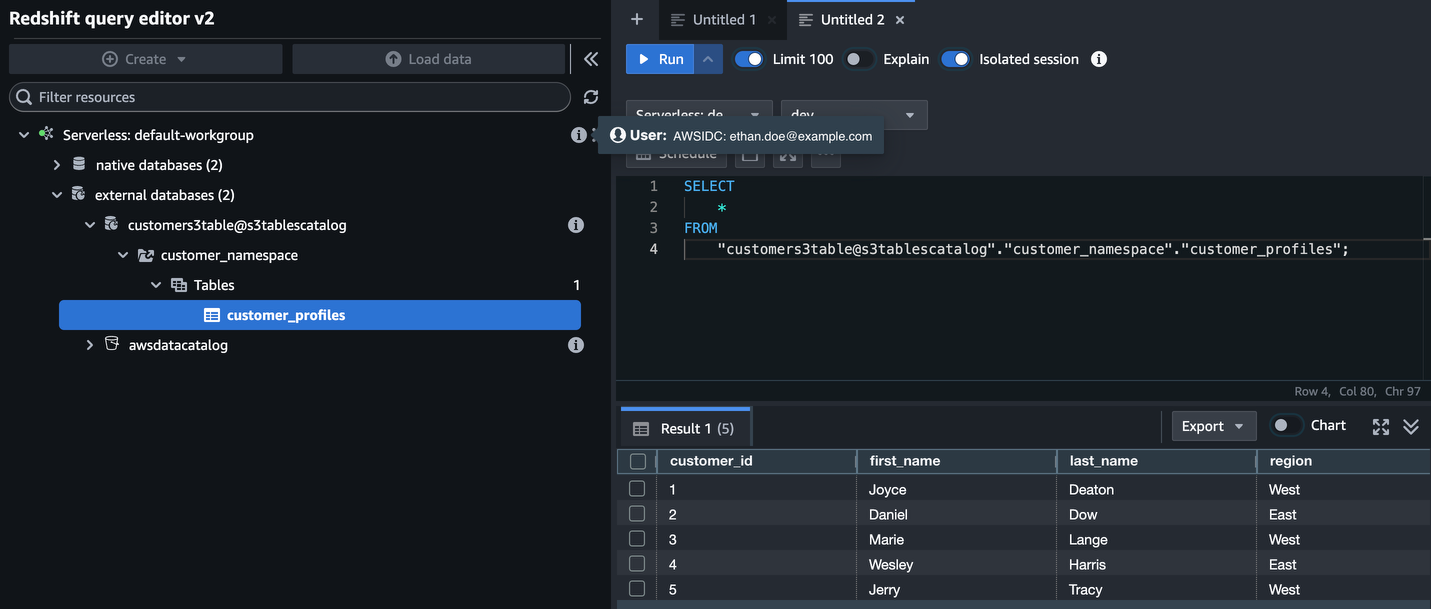
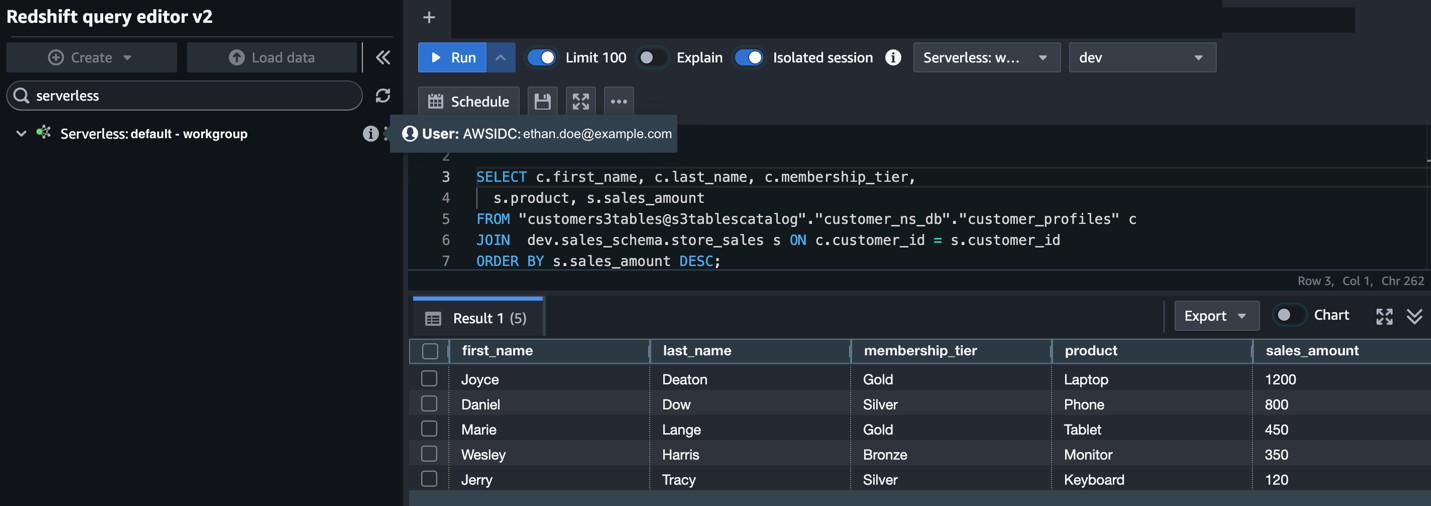
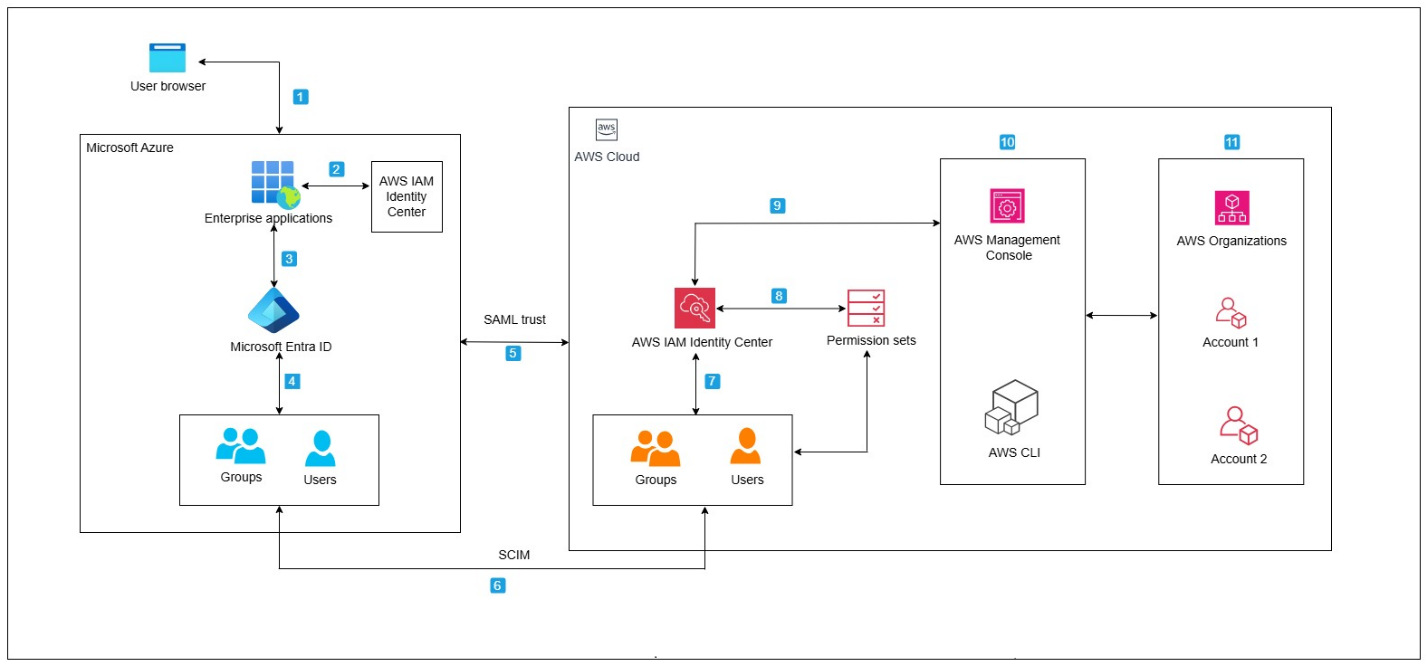
 Figure 7 – Successful AWS Glue job creation with configured parameters for the developer usage profile
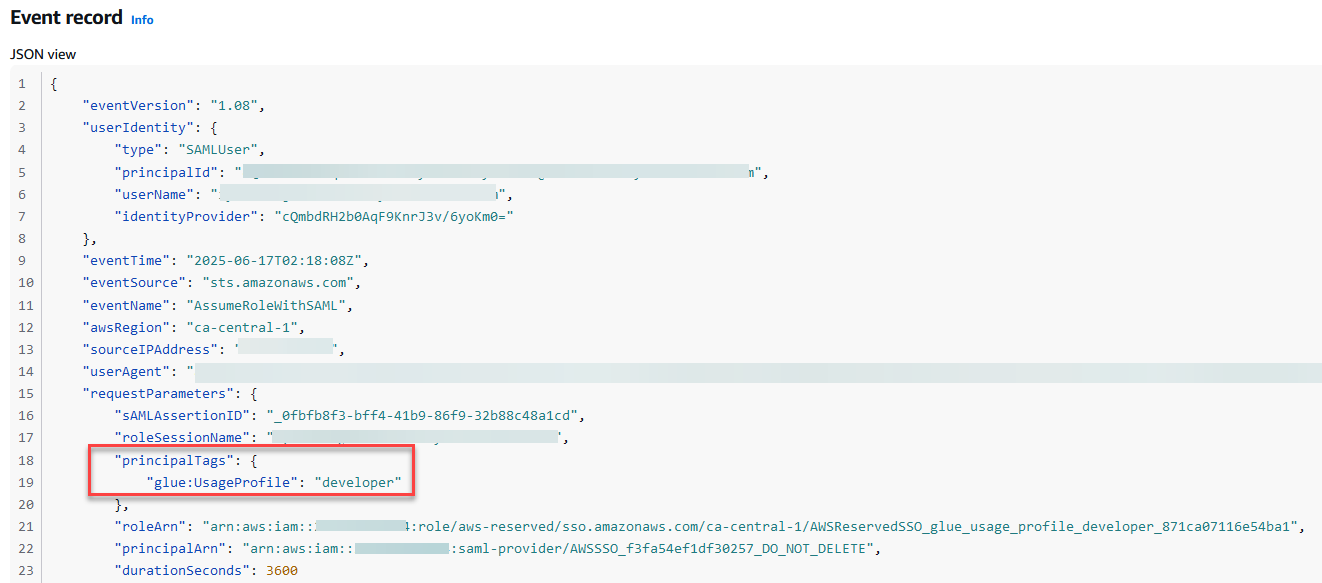
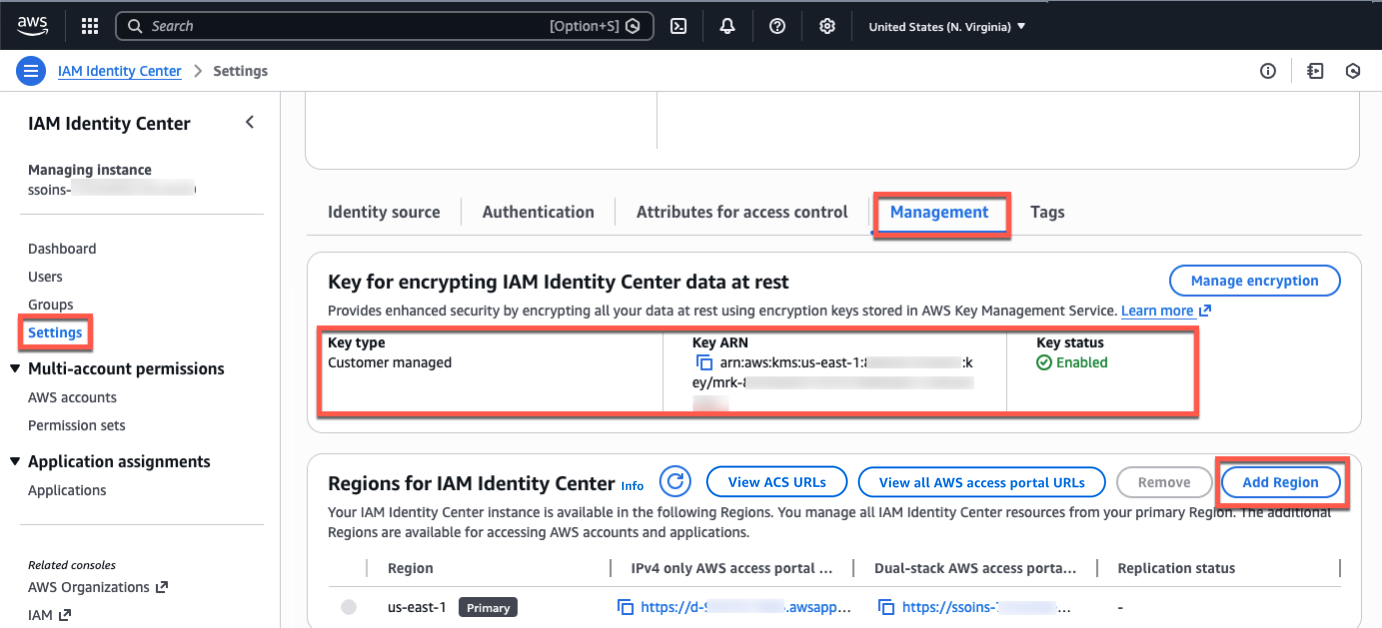
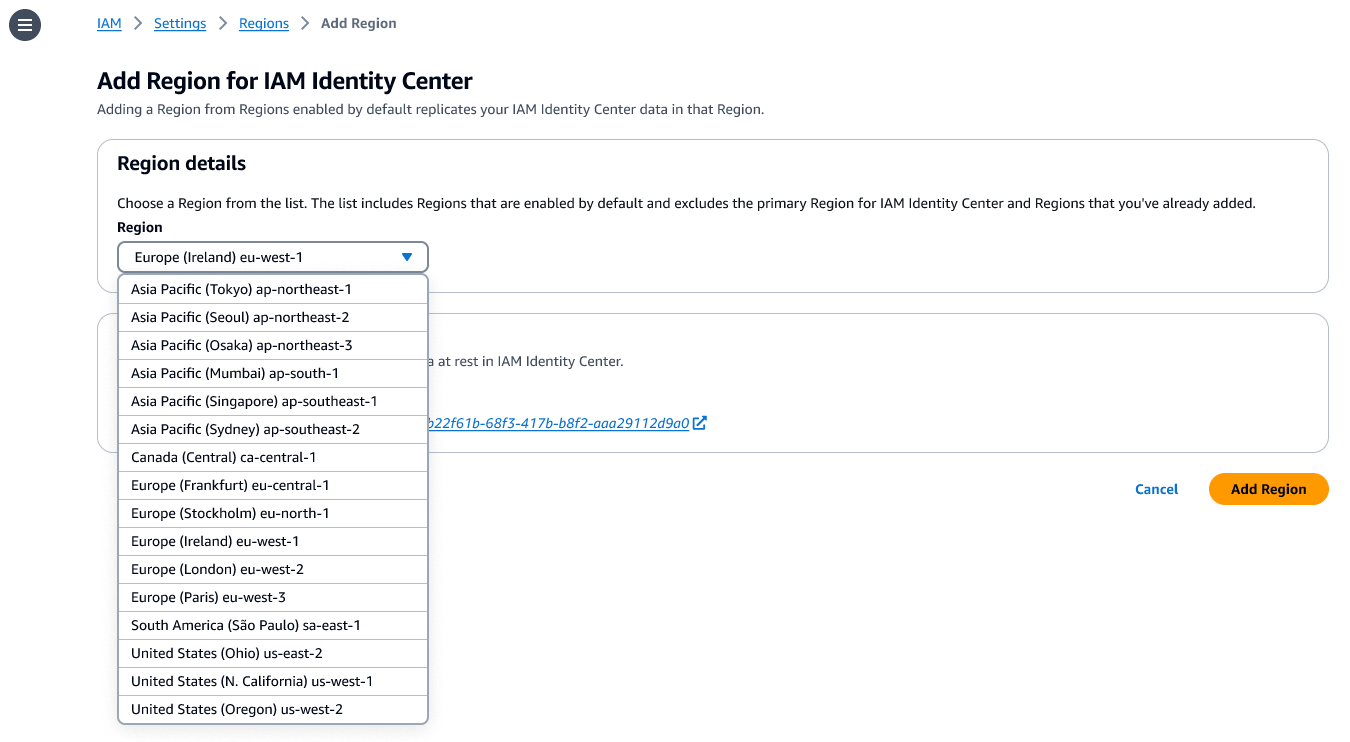
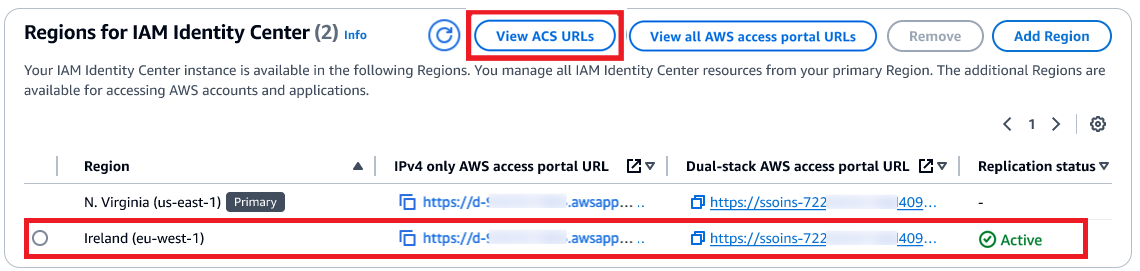
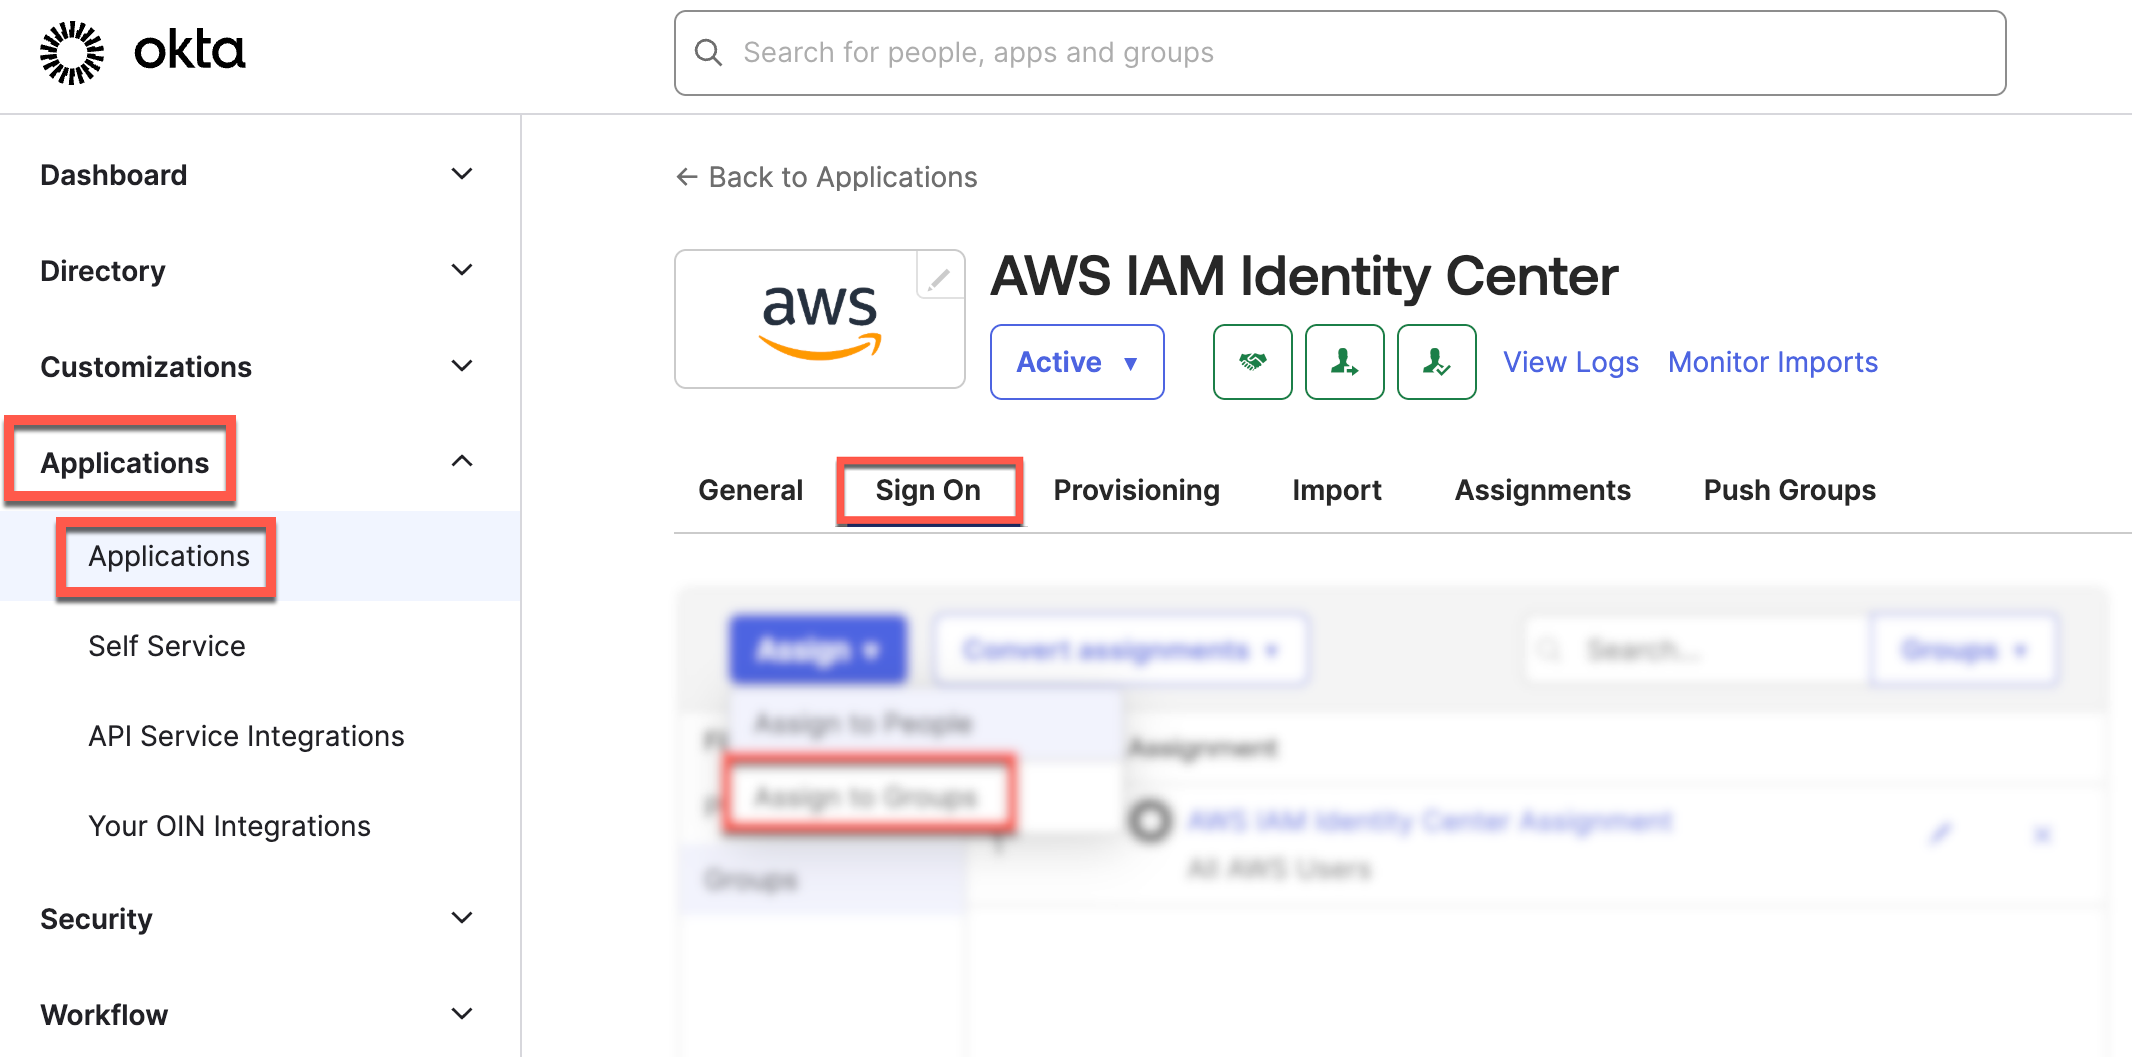
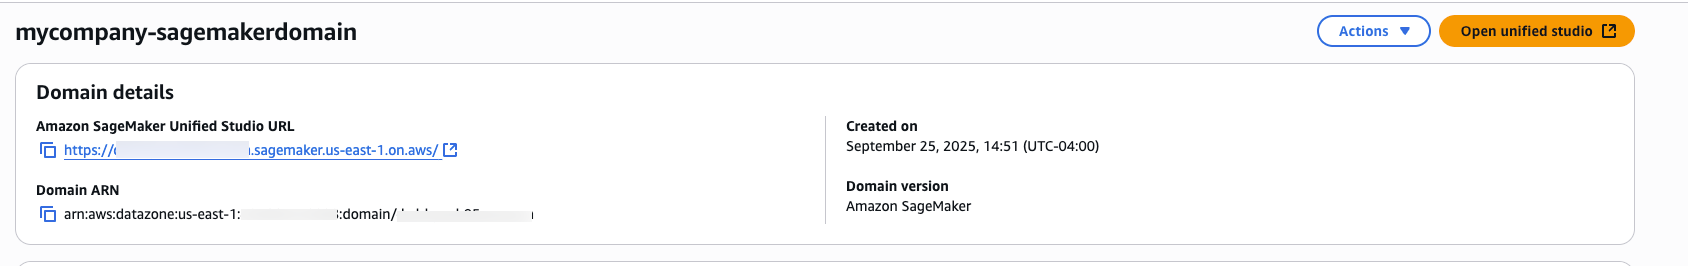
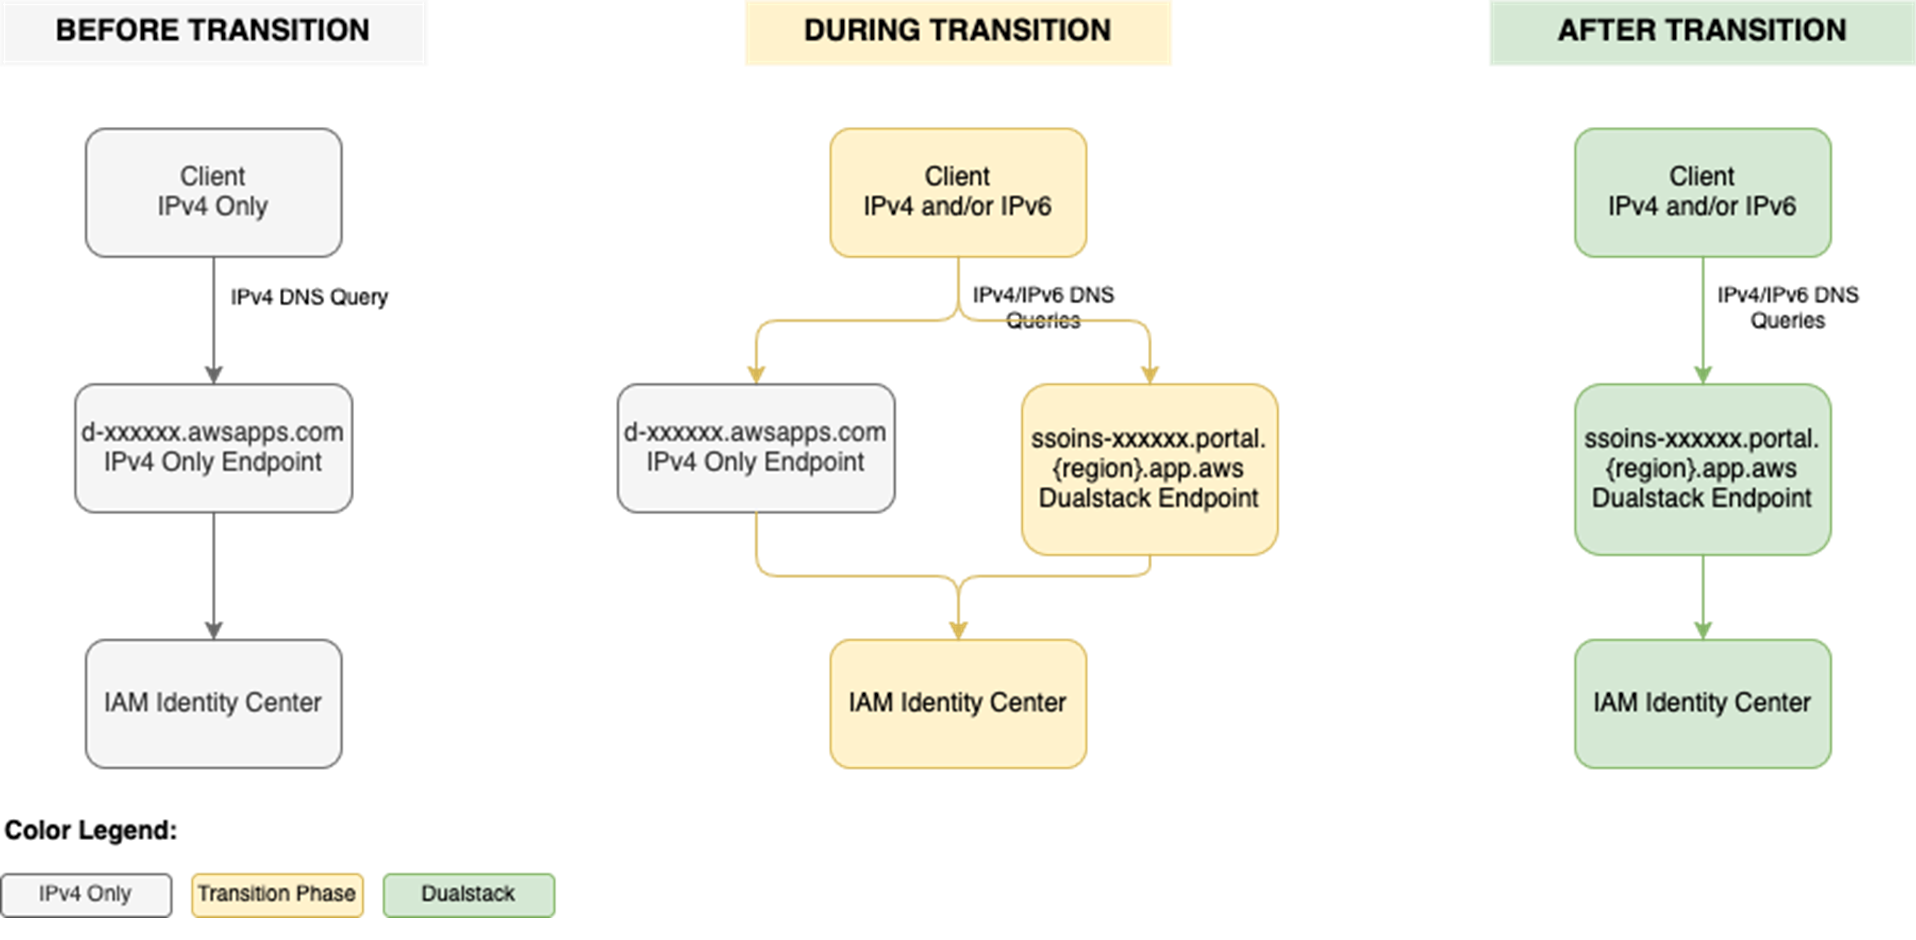
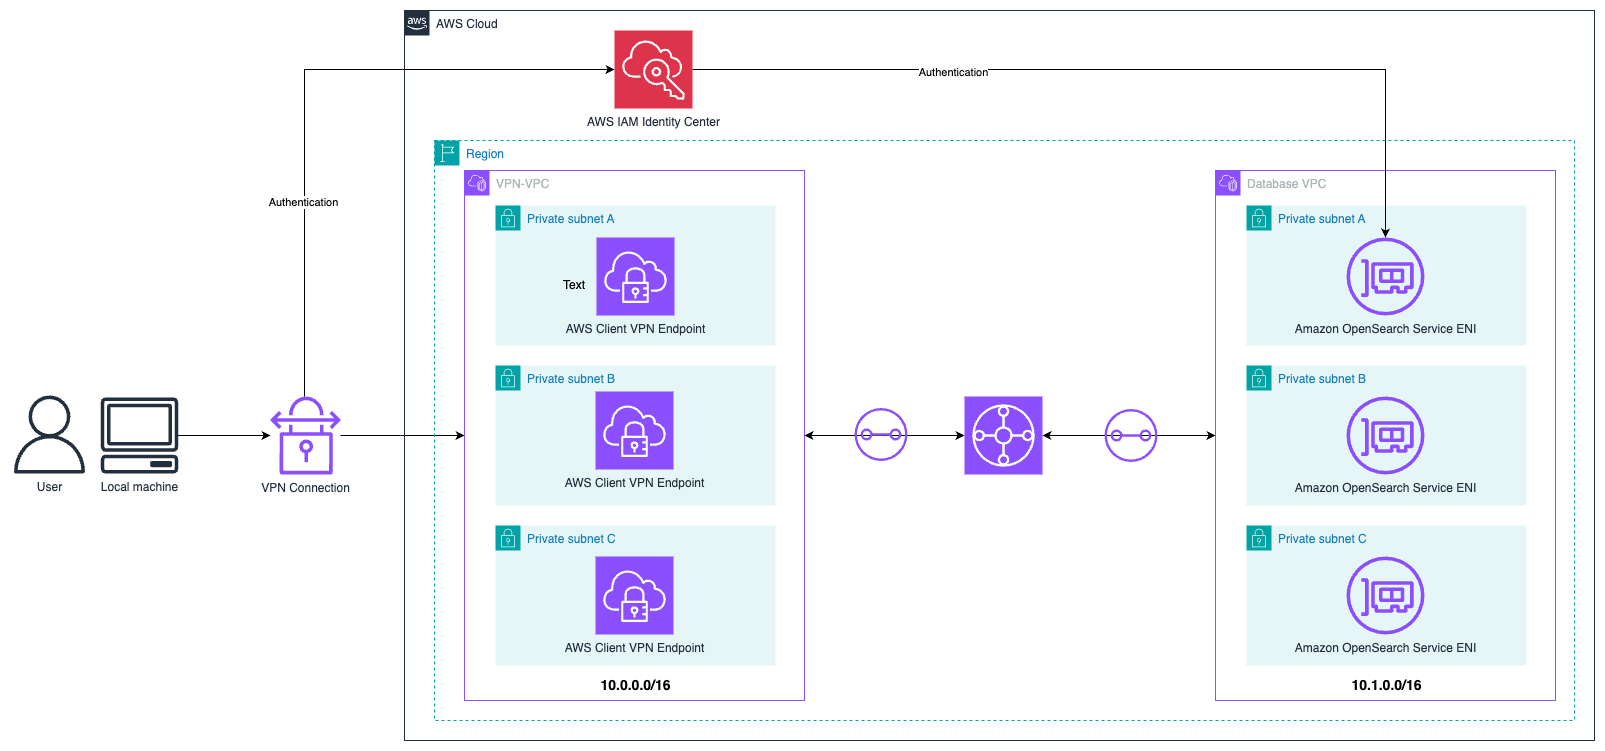
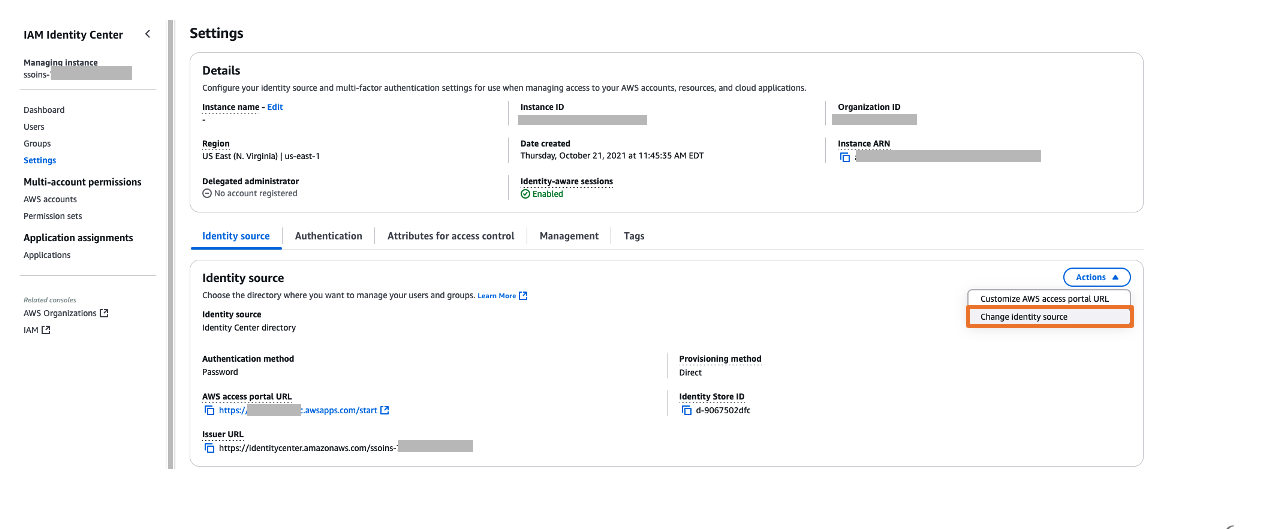 Figure 5: Selecting identity source in AWS IAM Identity Center
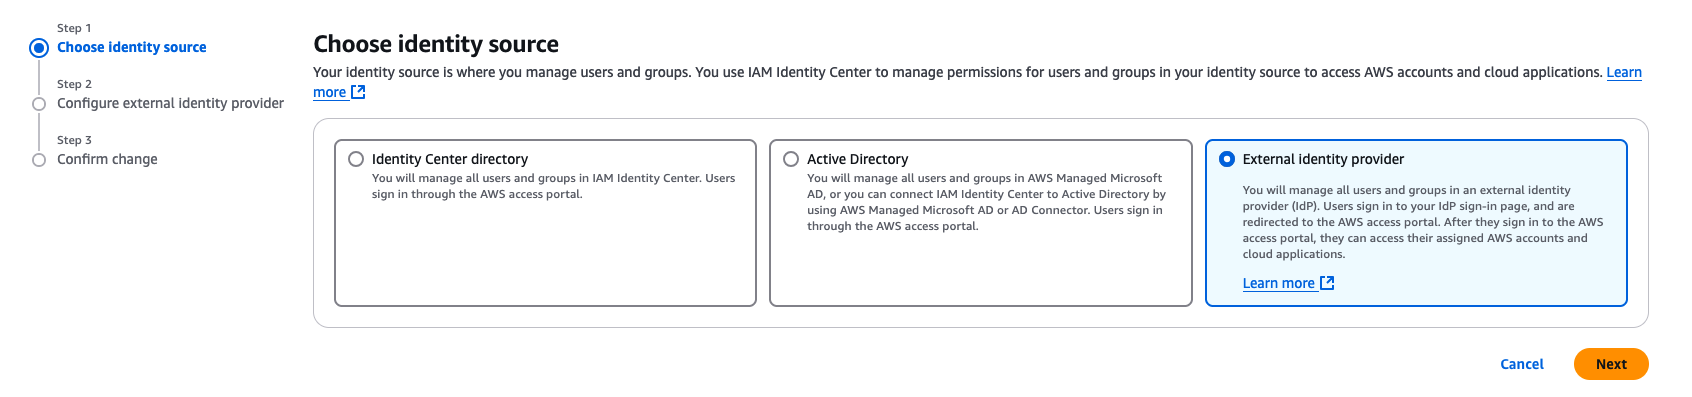
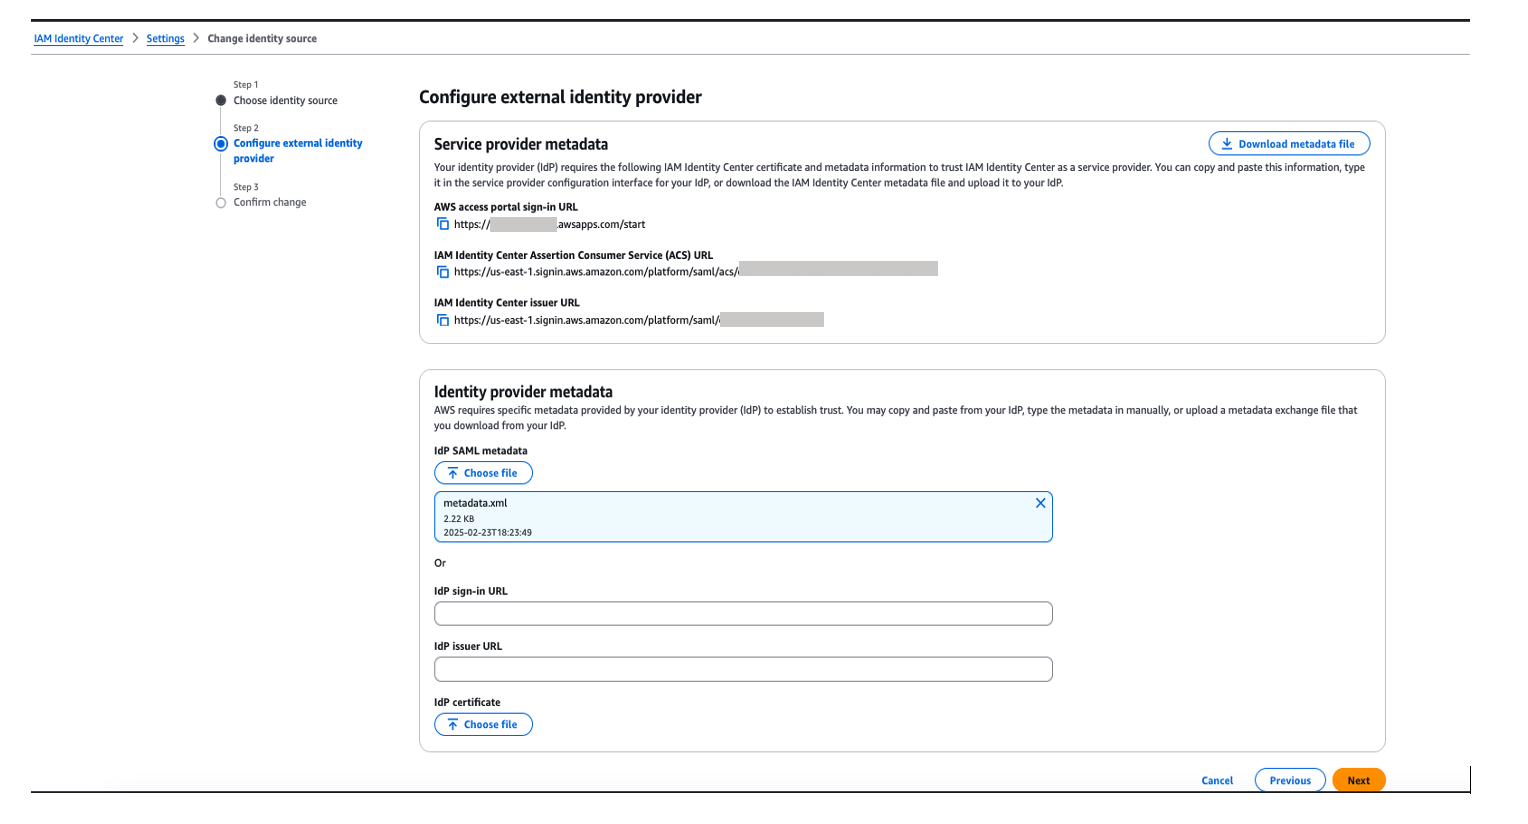
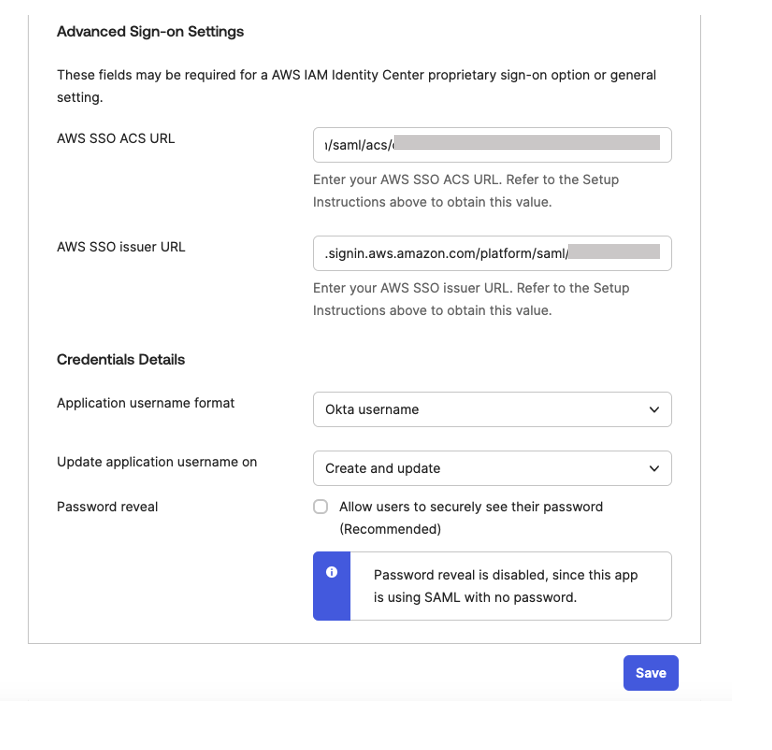 Figure 8. Configuring okta sign-on settings
 Figure 10. Automatic provisioning configuration parameters in AWS IAM Identity Center
 Figure 13: Assigning unifiedstudio group to SAML application called unifiedstudio



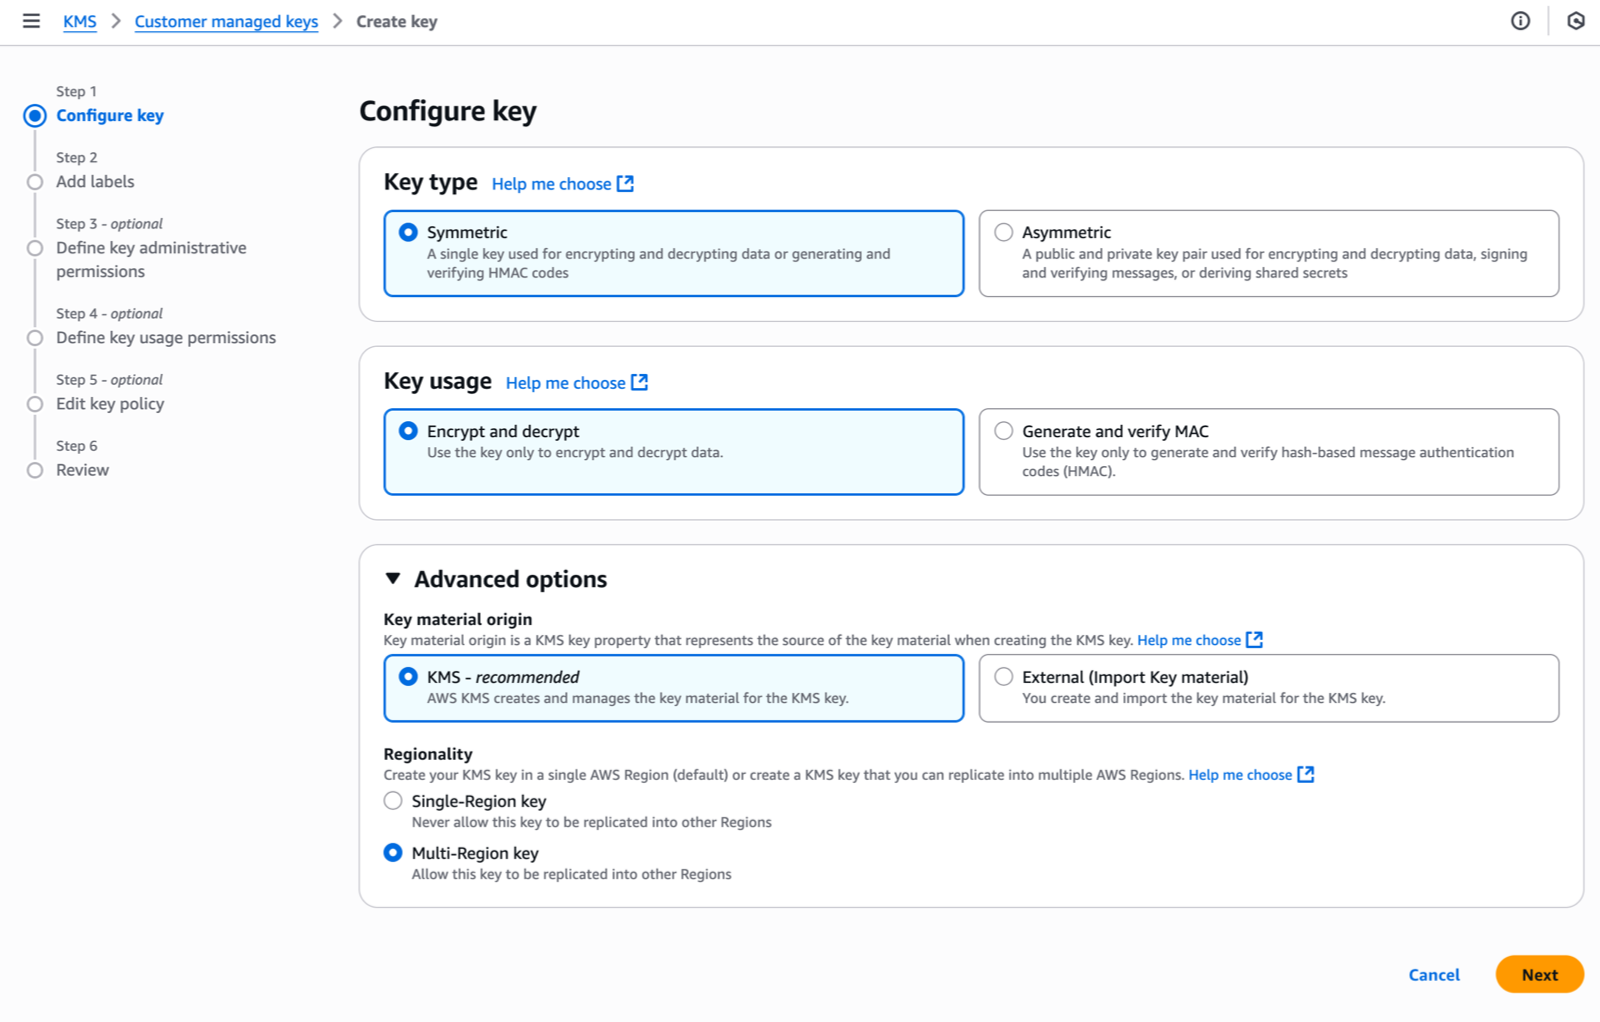
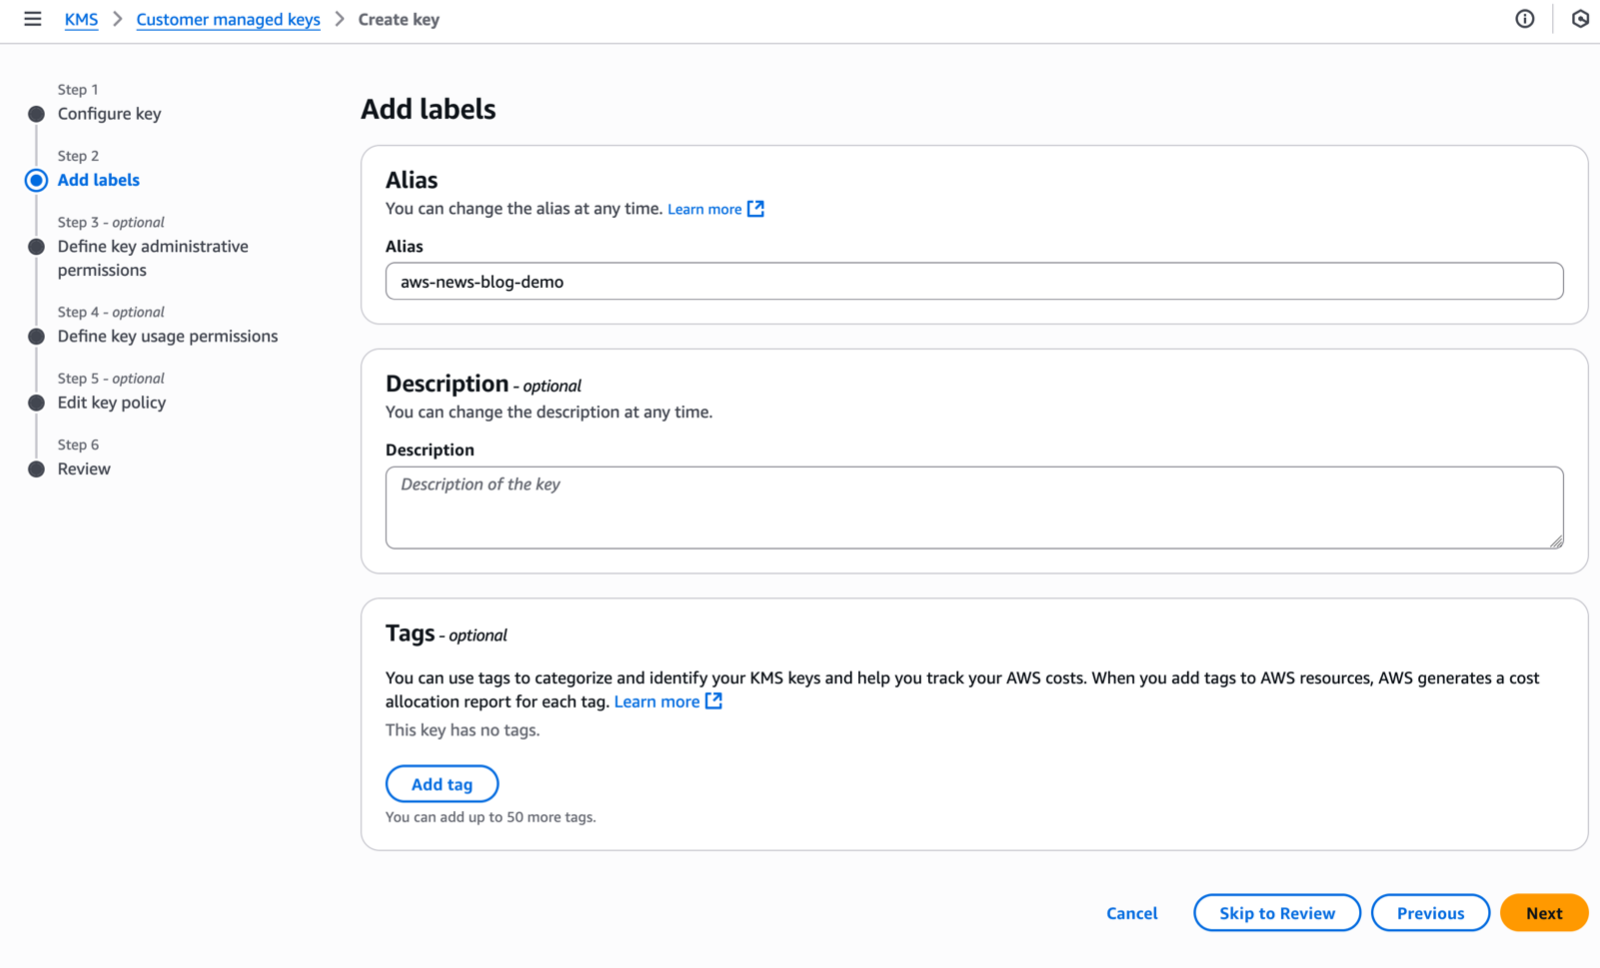
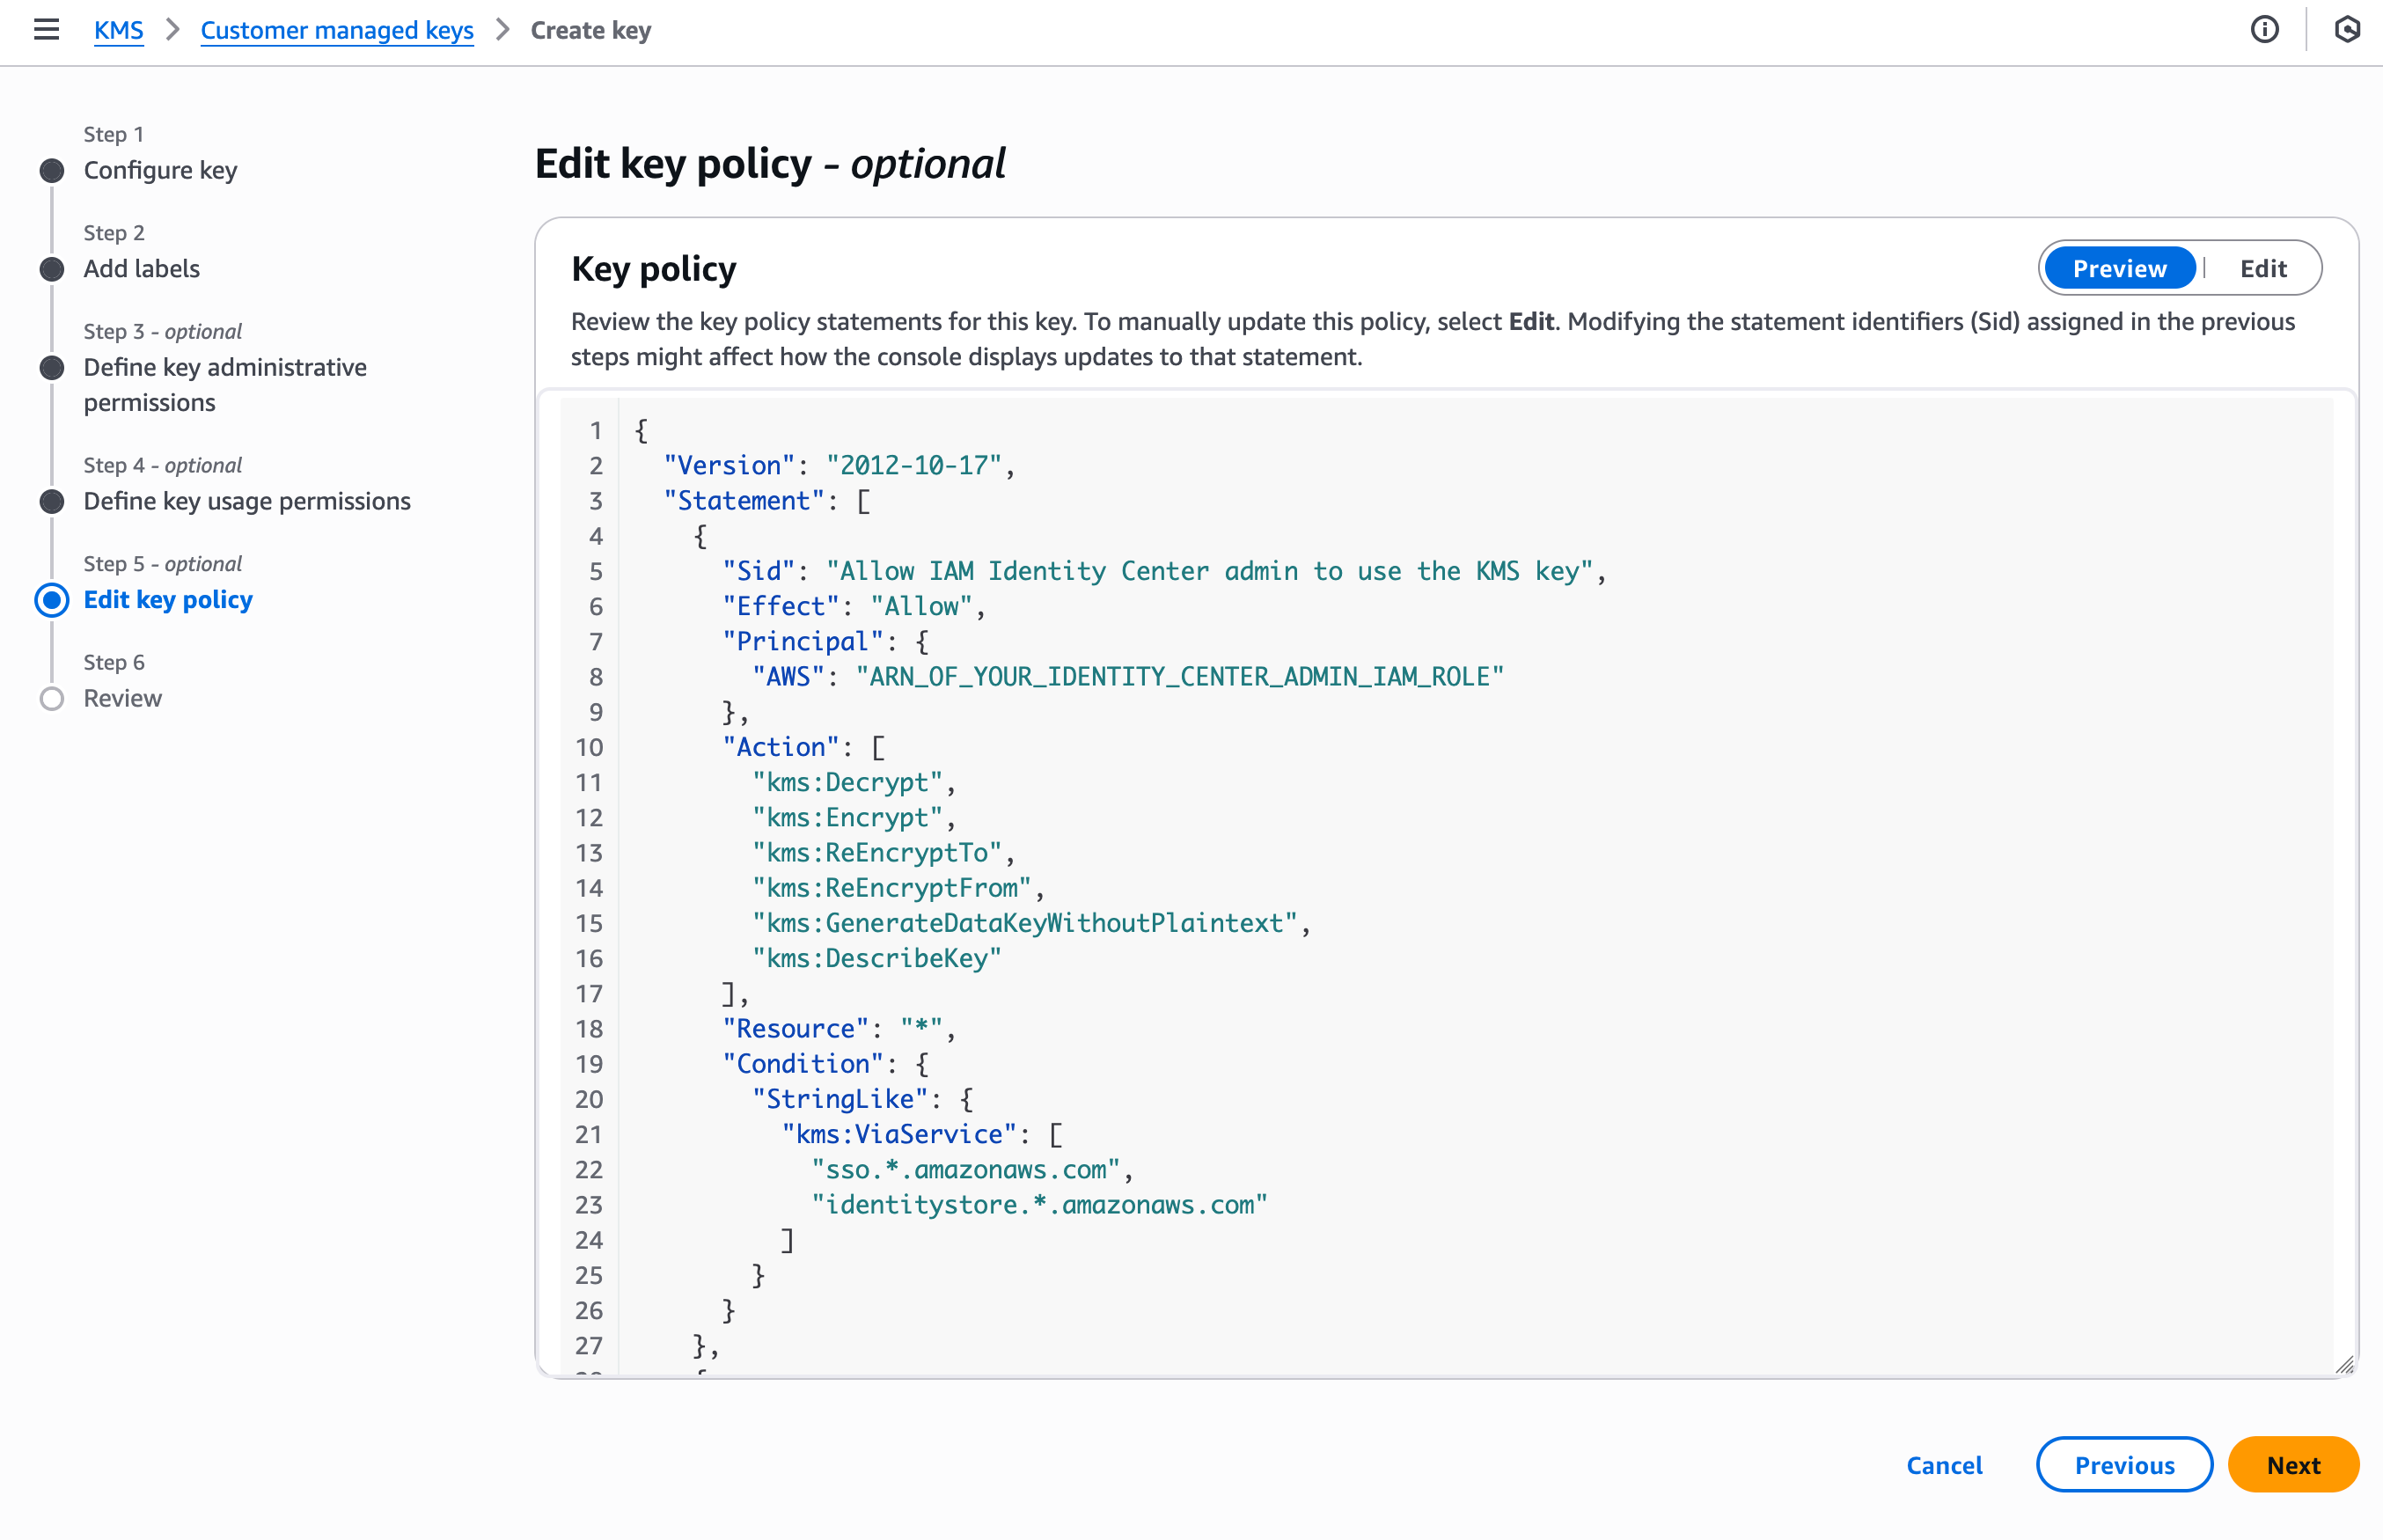
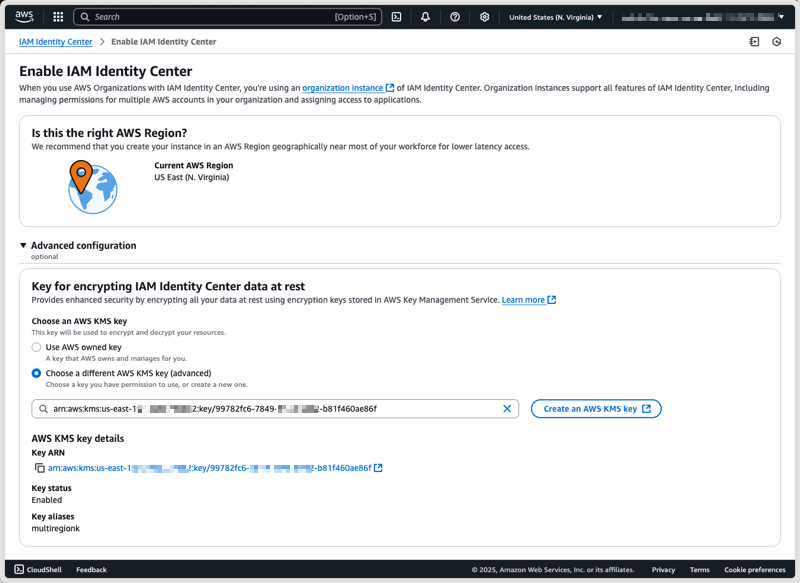
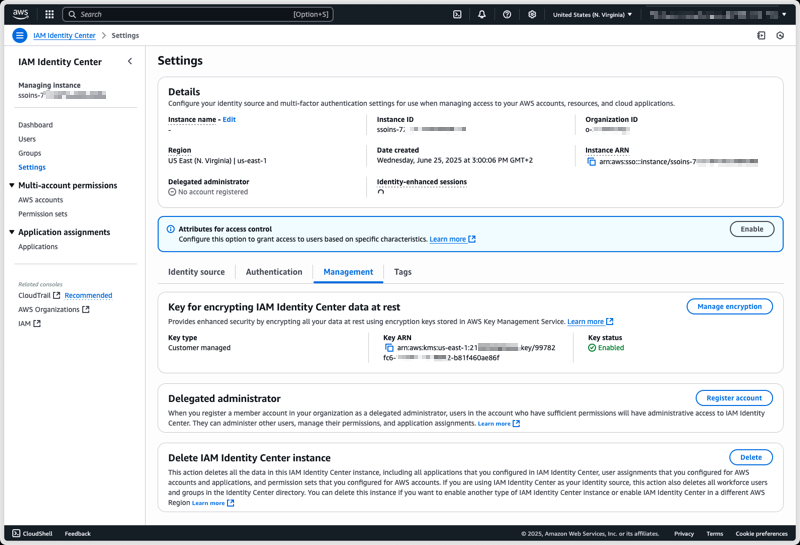
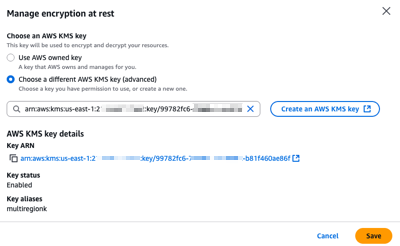
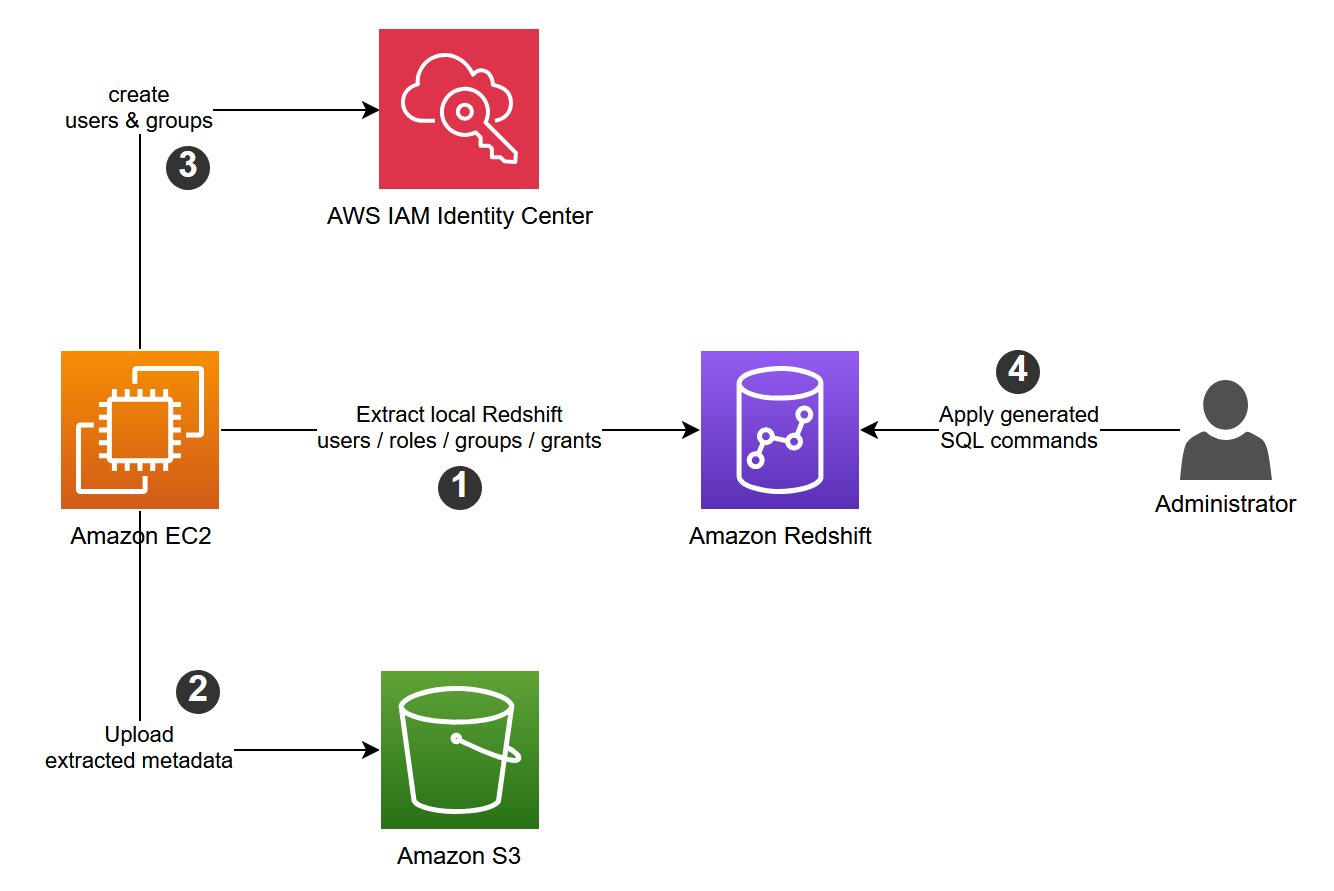
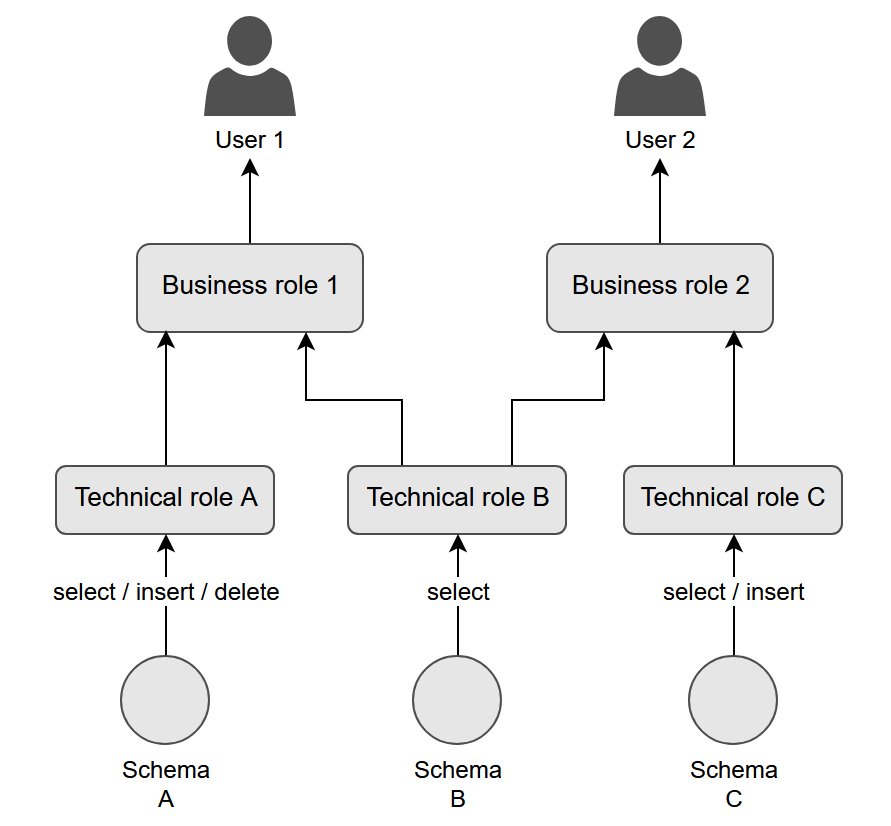
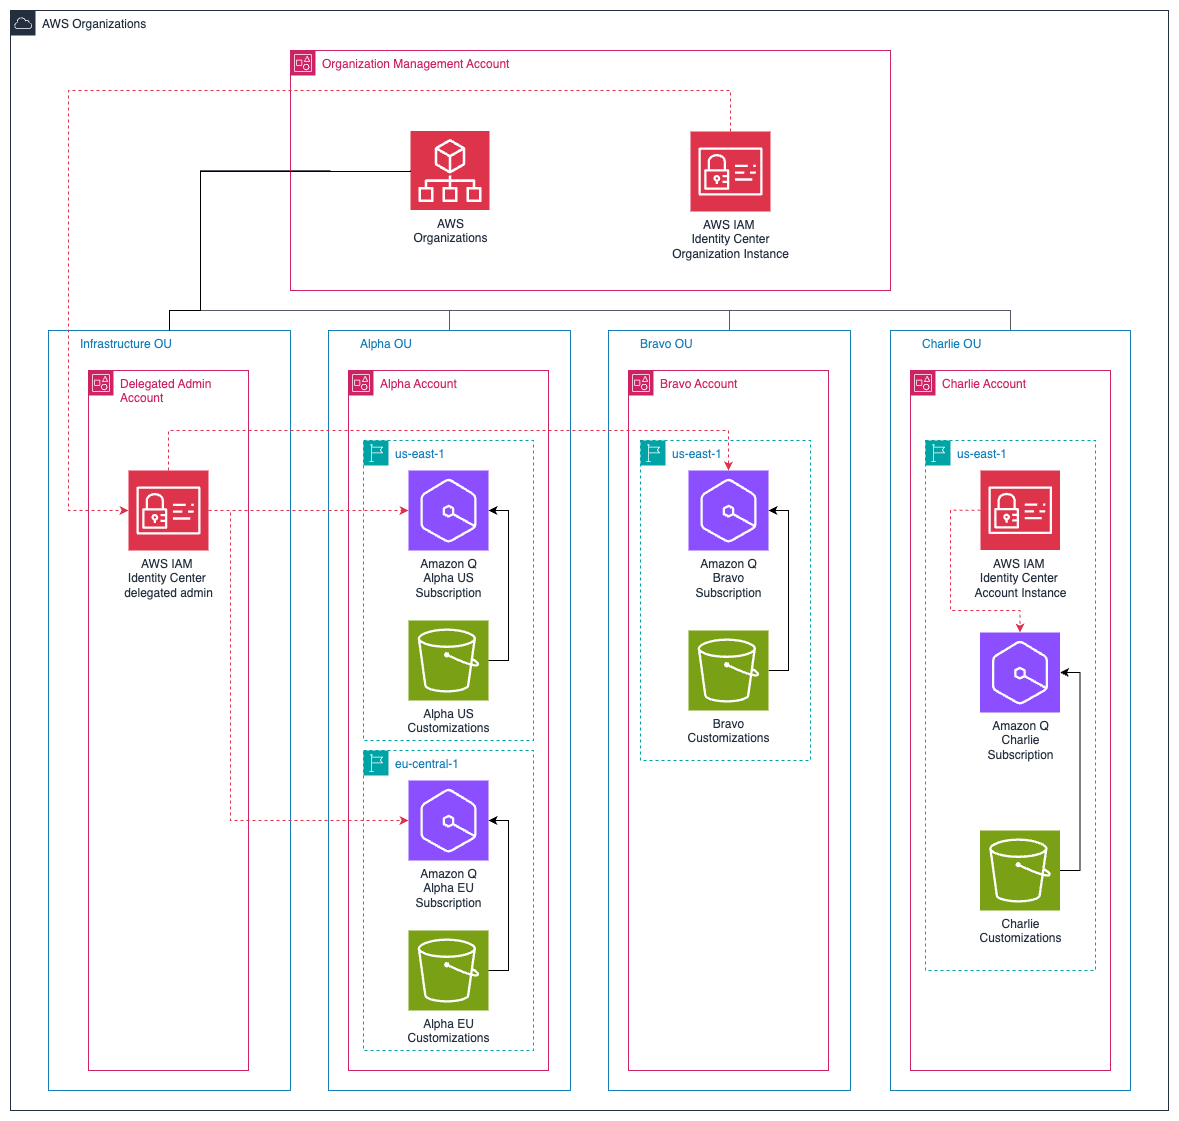
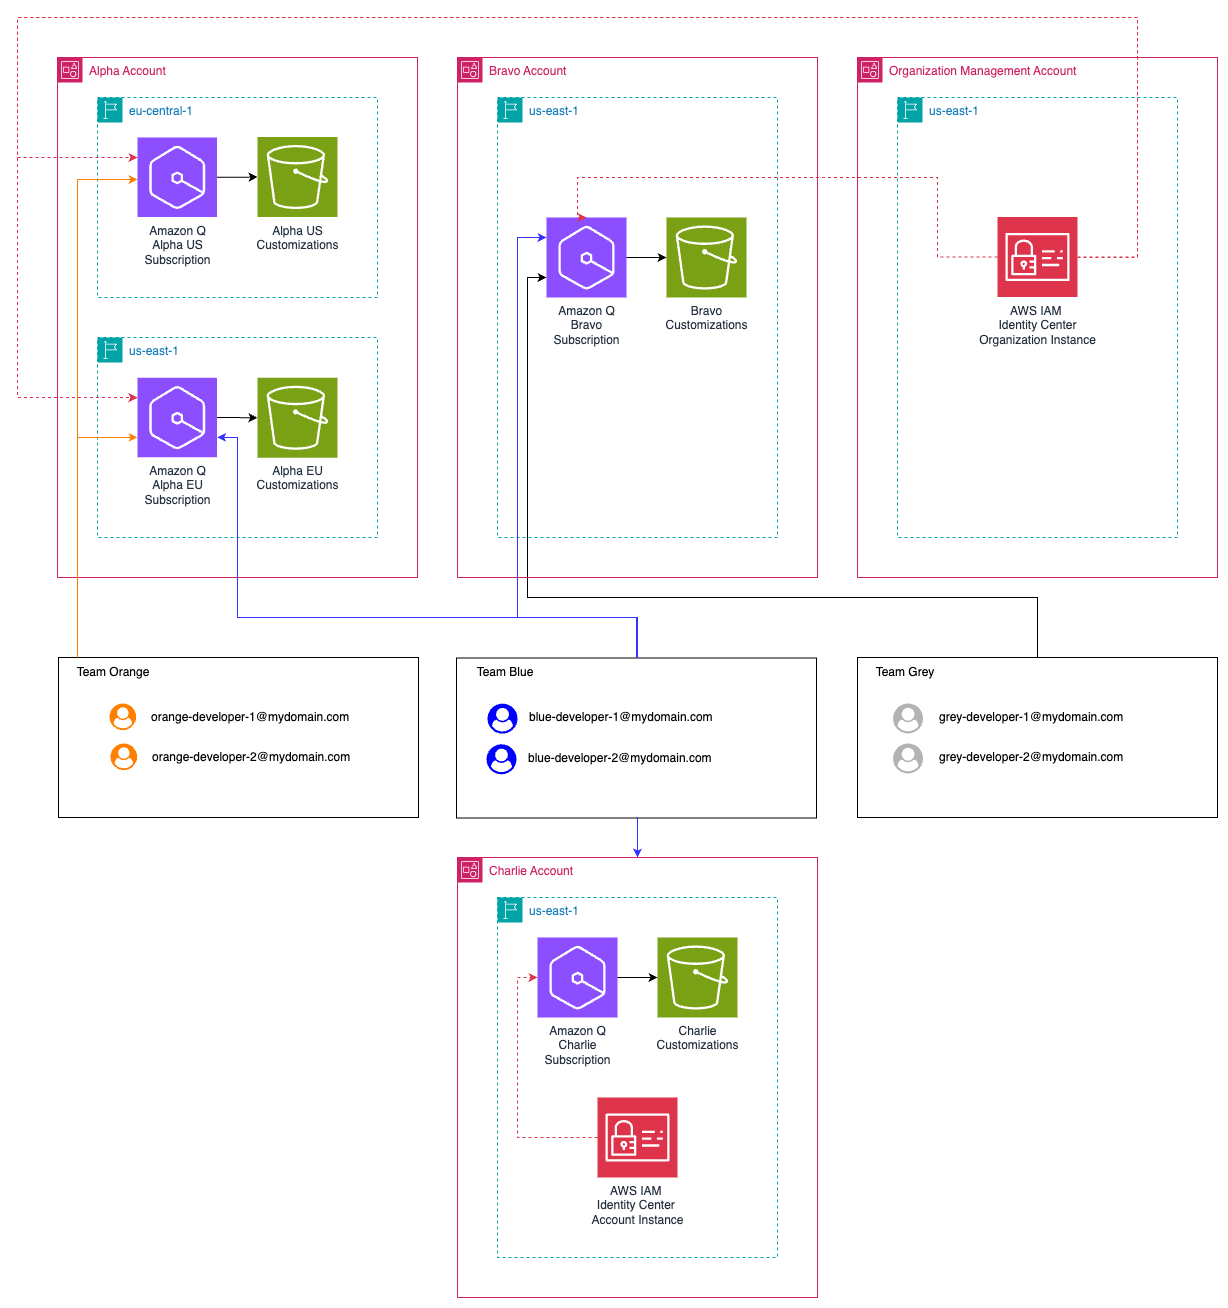


 Sid Vantair is a Solutions Architect with AWS covering Strategic accounts. He thrives on resolving complex technical issues to overcome customer hurdles. Outside of work, he cherishes spending time with his family and fostering inquisitiveness in his children.


 Venkata Sai Mahesh Swargam is a Cloud Engineer at AWS in Hyderabad. He specializes in Amazon MSK and Amazon Kinesis services. Mahesh is dedicated to helping customers by providing technical guidance and solving issues related to their Amazon MSK architectures. In his free time, he enjoys being with family and traveling around the world.


