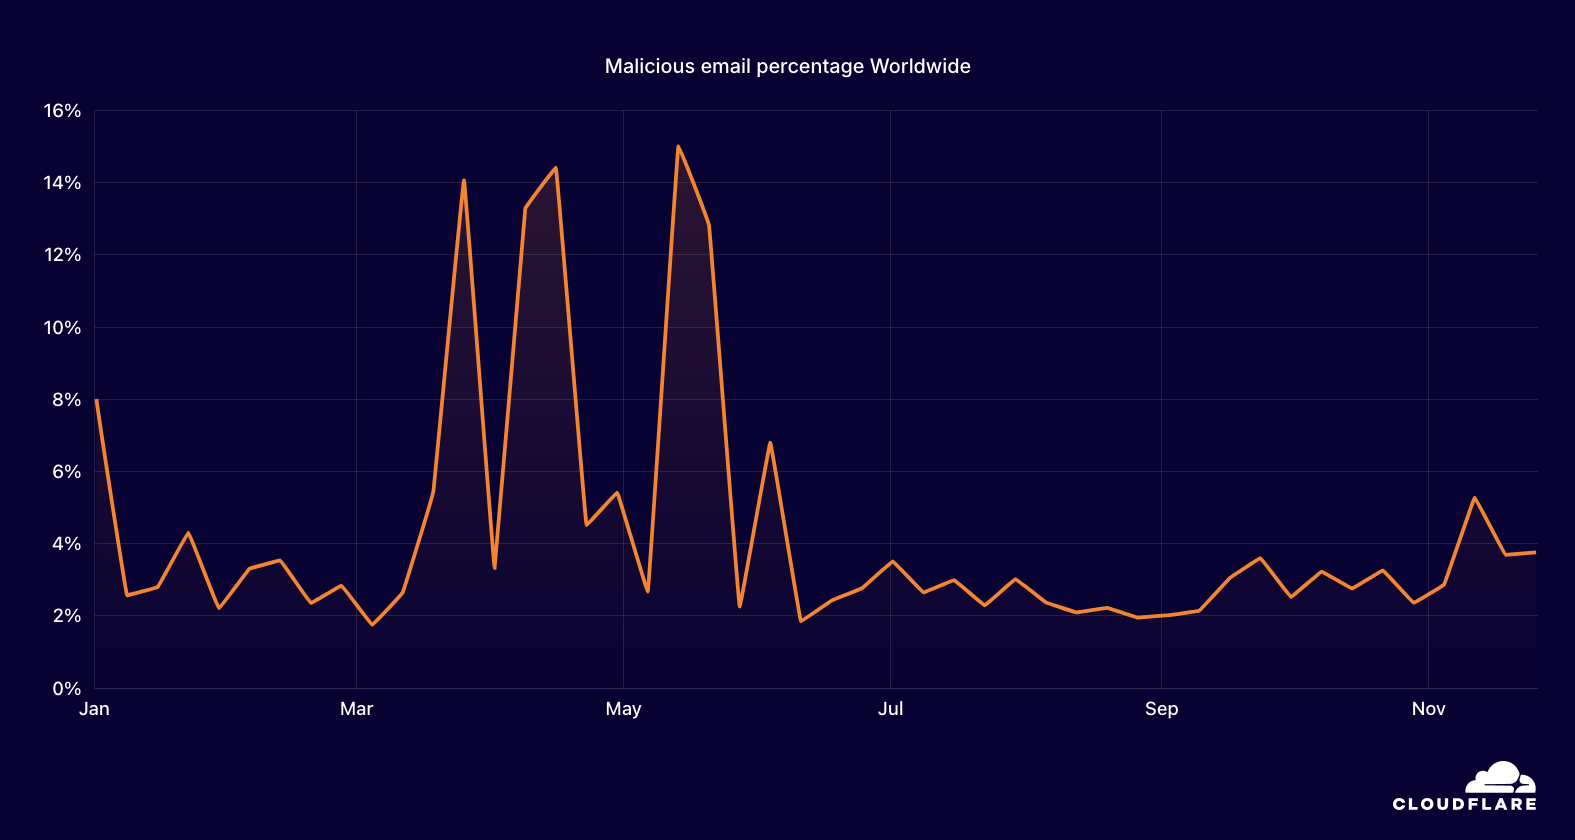
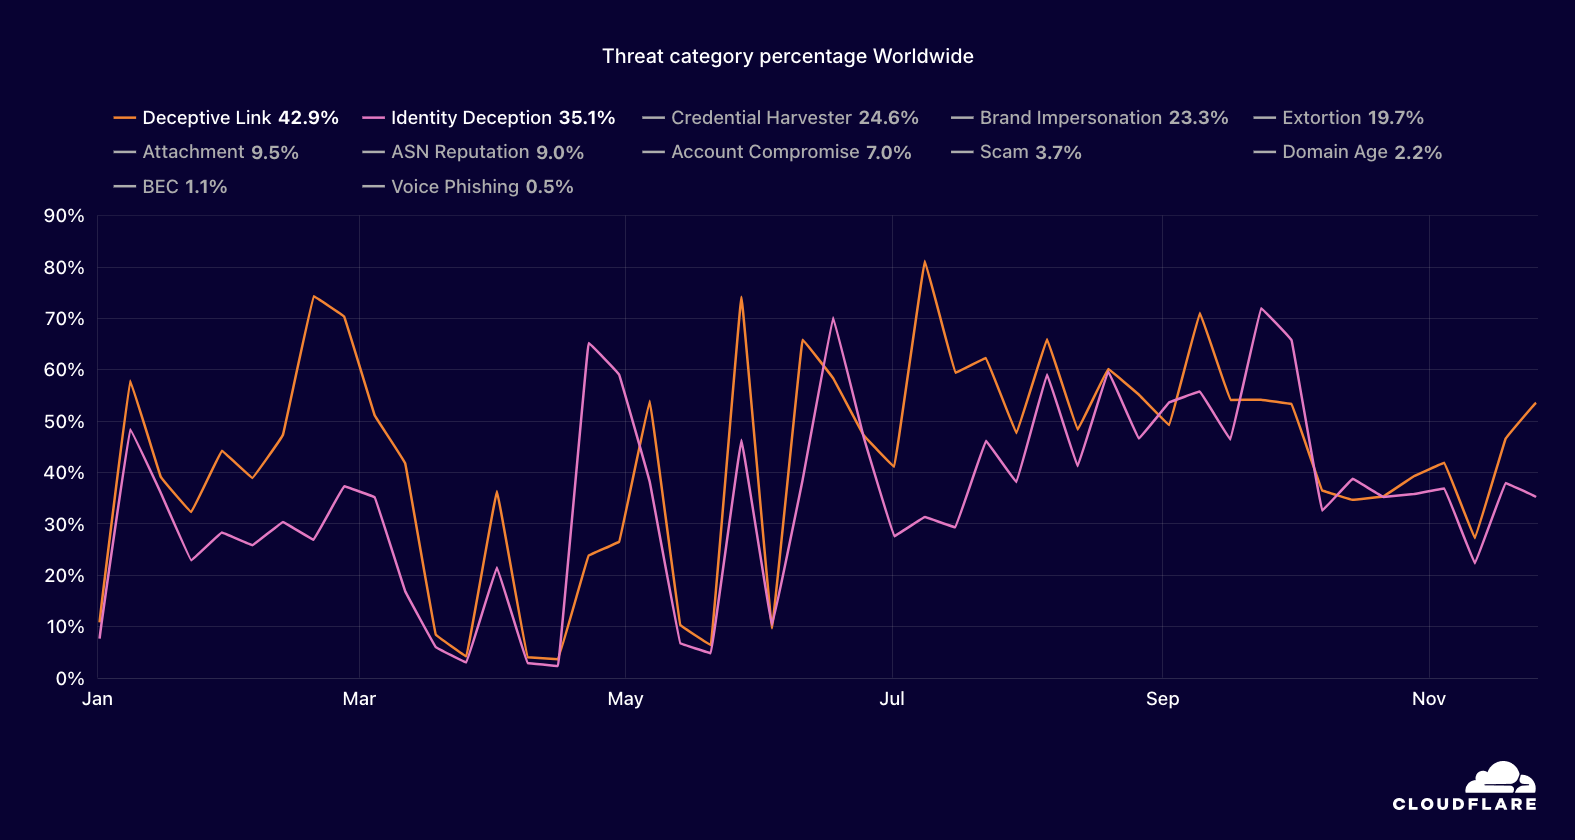
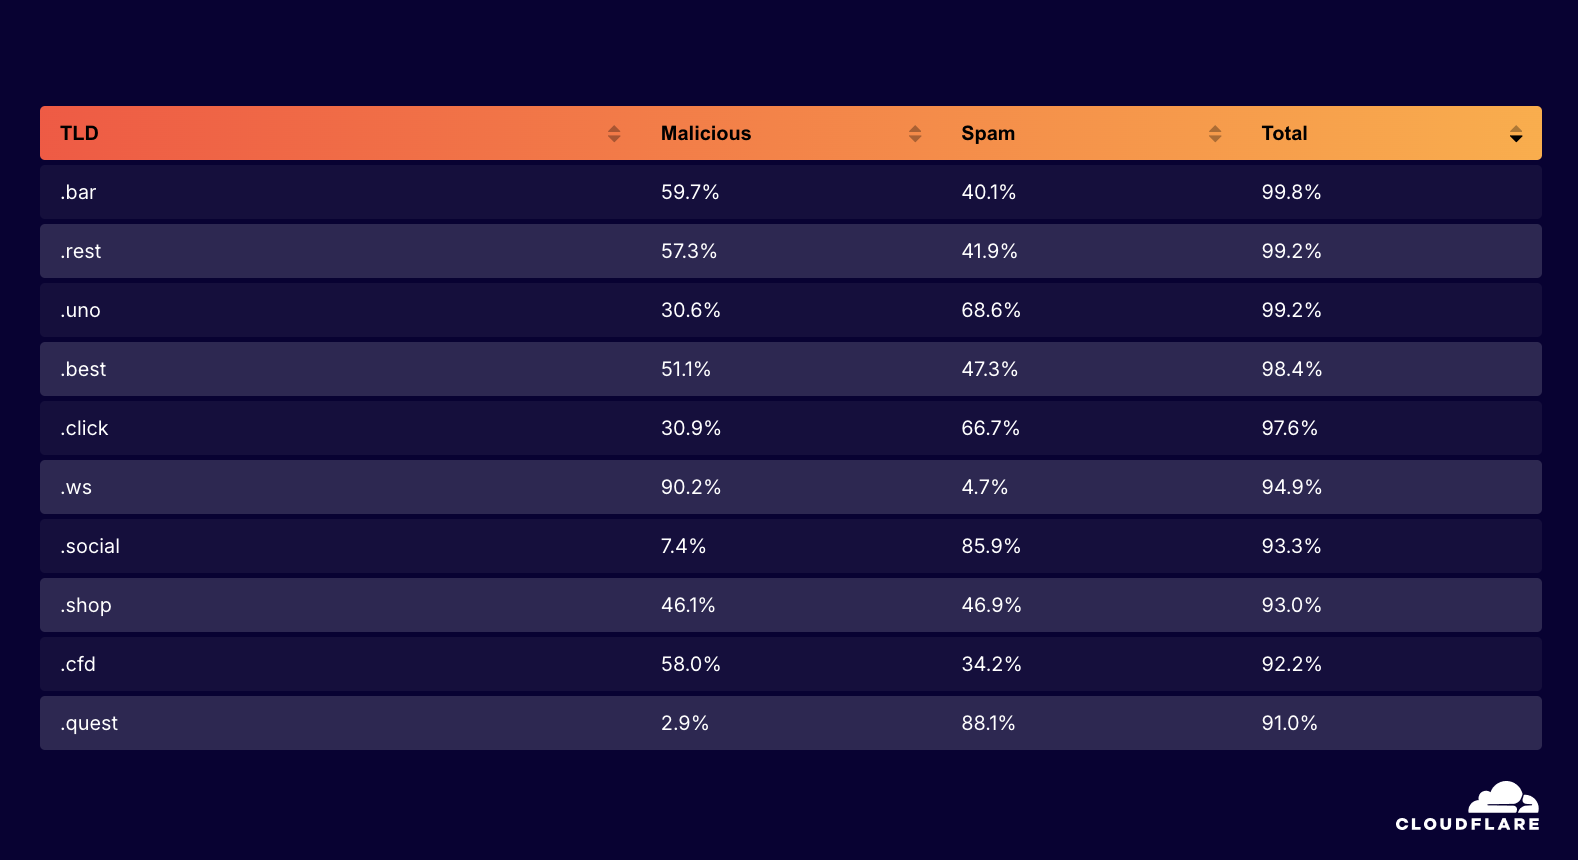
On Monday, December 9, multiple security firms began privately circulating reports of in-the-wild exploitation targeting Cleo file transfer software. Late the evening of December 9, security firm Huntress published a blog on active exploitation of three different Cleo products (docs):
Cleo VLTrader, a server-side solution for “mid-enterprise organizations”
Cleo Harmony, which provides file transfer capabilities for “large enterprises”
Cleo LexiCom, a desktop-based client for communication with major trading networks
Huntress’s blog says the exploitation they’re seeing across Cleo products results from an insufficient patch for CVE-2024-50623, a vulnerability disclosed in Cleo VLTrader, Cleo Harmony, and Cleo LexiCom in October 2024. Cleo indicated that the vulnerability was fixed in version 5.8.0.21 of all three solutions, but according to Huntress, 5.8.0.21 remains vulnerable to exploitation. CVE-2024-50623 is a cross-site scripting issue (CWE-79) that allows for unauthenticated remote code execution on target systems.
Update: Cleo evidently communicated with customers on December 10 acknowledging a “critical vulnerability in Cleo Harmony, VLTrader, and LexiCom that could allow an unauthenticated user to import and execute arbitrary bash or PowerShell commands on the host system by leveraging the default settings of the Autorun directory.”
As of December 10, Rapid7 MDR has confirmed successful exploitation of this issue in customer environments; similar to Huntress, our team has observed enumeration and post-exploitation activity and is investigating multiple incidents.
File transfer software continues to be a target for adversaries, and for financially motivated threat actors in particular. Rapid7 recommends taking emergency action to mitigate risk related to this threat.
Mitigation guidance
The following products and versions are vulnerable to CVE-2024-50623. The information below contradicts previous vendor guidance, which indicated that 5.8.0.21 resolved the issue. Cleo has updated their advisory as of December 10, 2024 to confirm 5.8.0.21 is still vulnerable.
Cleo Harmony before and including version 5.8.0.21
Cleo VLTrader before and including version 5.8.0.21
Cleo LexiCom before and including version 5.8.0.21
According to Huntress, “Cleo is preparing a new CVE designation and expects a new patch to be released mid-week.”
In the absence of an effective patch for CVE-2024-50623 (and any other CVEs that may be assigned to this exploit), Cleo customers should remove affected products from the public internet, ensuring they are behind a firewall. Per Huntress’s investigation, disabling Cleo’s Autorun Directory, which allows command files to be automatically processed, may also prevent the latter part of the attack chain from being executed.
Huntress’s blog has several descriptions of post-exploitation activity, including attack chain artifacts, commands run, and files dropped for persistence. Rapid7 recommends that affected customers review these indicators and investigate their environments for suspicious activity dating back to at least December 3, 2024.
Rapid7 customers
InsightVM and Nexpose customers will be able to assess their exposure to CVE-2024-50623 on Windows with an authenticated vulnerability check expected to be available in today’s (Tuesday, December 10) content release. Please note that content releases are typically available late in the evening ET on Patch Tuesday.
InsightIDR and Managed Detection and Response customers have existing detection coverage through Rapid7’s expansive library of detection rules. Rapid7 recommends installing the Insight Agent on all applicable hosts to ensure visibility into suspicious processes and proper detection coverage. Below is a non-exhaustive list of rules deployed and alerting on behavior related to this threat:
Suspicious Process – XORed Data in PowerShell
Suspicious Process – PowerShell System.Net.Sockets.TcpClient
Attacker Behavior – Possible Cleo MFT Exploitation 2024
Cloudflare’s AI Audit dashboard allows you to easily understand how AI companies and services access your content. AI Audit gives a summary of request counts broken out by bot, detailed path summaries for more granular insights, and the ability to filter by categories like AI Search or AI Crawler.
Today, we’re going one step further. You can now quickly see which AI services are honoring your robots.txt policies, which aren’t, and then programmatically enforce these policies.
What is robots.txt?
Robots.txt is a plain text file hosted on your domain that implements the Robots Exclusion Protocol, a standard that has been around since 1994. This file tells crawlers like Google, Bing, and many others which parts of your site, if any, they are allowed to access.
There are many reasons why site owners would want to define which portions of their websites crawlers are allowed to access: they might not want certain content available on search engines or social networks, they might trust one platform more than another, or they might simply want to reduce automated traffic to their servers.
With the advent of generative AI, AI services have started crawling the Internet to collect training data for their models. These models are often proprietary and commercial and are used to generate new content. Many content creators and publishers that want to exercise control over how their content is used have started using robots.txt to declare policies that cover these AI bots, in addition to the traditional search engines.
Here’s an abbreviated real-world example of the robots.txt policy from a top online news site:
This policy declares that the news site doesn’t want ChatGPT, Anthropic AI, Google Gemini, or ByteDance’s Bytespider to crawl any of their content.
From voluntary compliance to enforcement
Compliance with the Robots Exclusion Protocol has historically been voluntary.
That’s where our new feature comes in. We’ve extended AI Audit to give our customers both the visibility into how AI services providers honor their robots.txt policies and the ability to enforce those policies at the network level in your WAF.
Your robots.txt file declares your policy, but now we can help you enforce it. You might even call it … your Robotcop.
How it works
AI Audit takes the robots.txt files from your web properties, parses them, and then matches their rules against the AI bot traffic we see for the selected property. The summary table gives you an aggregated view of the number of requests and violations we see for every Bot across all paths. If you hover your mouse over the Robots.txt column, we will show you the defined policies for each Bot in the tooltip. You can also filter by violations from the top of the page.
In the “Most popular paths” section, whenever a path in your site gets traffic that has violated your policy, we flag it for visibility. Ideally, you wouldn’t see violations in the Robots.txt column — if you do see them, someone’s not complying.
But that’s not all… More importantly, AI Audit allows you to enforce your robots.txt policy at the network level. By pressing the “Enforce robots.txt rules” button on the top of the summary table, we automatically translate the rules defined for AI Bots in your robots.txt into an advanced firewall rule, redirect you to the WAF configuration screen, and allow you to deploy the rule in our network.
This is how the robots.txt policy mentioned above looks after translation:
Once you deploy a WAF rule built from your robots.txt policies, you are no longer simply requesting that AI services respect your policy, you’re enforcing it.
Conclusion
With AI Audit, we are giving our customers even more visibility into how AI services access their content, helping them define their policies and then enforcing them at the network level.
This feature is live today for all Cloudflare customers. Simply log into the dashboard and navigate to your domain to begin auditing the bot traffic from AI services and enforcing your robots.txt directives.
It’s a video of someone trying on a variety of printed full-face masks. They won’t fool anyone for long, but will survive casual scrutiny. And they’re cheap and easy to swap.
Малко се говори за икономическата страна на падането на режима на Асад в Сирия. Повечко се коментира военната страна на конфликта, а то такава реално нямаше. Армията бе разпусната и Асад призова за мирно предаване на властта. Нещо повече – разпуснатите войници дори не унищожиха военната си техника, а я оставиха в ръцете на „враговете си“ което е немислимо в един военен кофликт. Това ме наведе на мисълта, че случващото се няма нищо общо с военните действия и се зарових в икономическите предпоставки.
Информацията, която намерих и обобщих е на база информация от мрежата, понеже официална статистика е до 2020 година, а във военни времена не е ясно колко е меродавна тази статистика.
Моля използвайте приложената форма за записване на час за среща
[contact-form-7]
Твърди се в медиите, че от няколко месеца армията на Асад е получавала по 35 долара на месец като заплата на глава. Сами разбираме, че с тези пари не може да се поддържат военни действия и войниците да са мотивирани. Лично аз предполагам, че е такова положението или поне близко до това, понеже вторият по големина град – Алепо, което е и индустриалното сърце на Сирия, отдавна е под турски контрол. Твърди се, че там официална валута е турската лира. Също така за петролните кладенци в провинцията Идлиб има изписано доста, как Сирия предявява претенции към САЩ, после към Турция… Да не забравяме и санкциите от САЩ
Осен всичко това, плодородните земи също от дълго време са в ръцете на Турция и кюрдите. С две думи Сирия няма от какво да издържа армията и режима си.
Моето мнение е, че това бяха руснаците. Те имаха най-голям интерес от този режим, но с войната в Украйна, явно вече им стана неизгодно да плащат за издръжка на режима, само и само да имат 2 бази в Сирия. Верно е, че са стратегически, но пък всичко е въпрос на средства. Ако е прекалено скъпо, то не може да е вечно.
Турция от своя страна приюти „демократичните ислямисти“ в лагери и ги обучава достатъчно дълго време, за да ги върне на терена. И докато повечето хора смятат, че големия печеливш е точно Турция, аз мисля, че не е така. Мисля че е Израел, защото на Турция и предстоят тежки времена с кюрдите, както и бъдещата издръжка на една цяла държава с население около 20 милиона. Казваме около, защото не знаем реално колко е към момента. Явно руснаците повече нма да плащат и оставят това право на Турция, което до момента само получаваше финансовите облаги от владеенето на териториите, но сега ще плаща за изграждане на държава, доколкото това е възможно изобщо. Предстои им и сбъсък с кюрдите, които пък са стратегически партньор на САЩ. А САЩ от своя страна е много малко вероятно да се включат финансово в издръжката на новата държава.
ЗАЩО Е ПЕЧЕЛИВШ ИЗРАЕЛ?
Защото въпреки, че декларира ненамеса в кофлита, това не им попречи да завземат южния военен пункт на сирийска територия, който имаше пряка видимост към Голанските възвишения, както и да нанесе въздушни удари по военни складове на сирийска територия за да не попаднат оржията в ръцете на джихадисти. Какви точно джихадисти, щом „демократичните ислямисти“ са взели властта – не се казва, но така или иначе оръжията са унищожени, а израелската войска е на сирийска територия.
КЪДЕ ЩЕ СЕ ДЕНЕ РУСИЯ?
Медиите твърдят, че транспортни самолети кацат в руските бази и изнасят оръжие и техника от там. Не е ясно каква е тази техника. Дали е от самите бази или от други по малки бази в страната. Твърди се също, че „демократичните ислямисти“ заобикалет руските воени бази.
При всички положения имаме освободена военна техника и предполагам не е сложно да предположим къде ще бъде разположена тя, ако базите бъдат закрити.
Казвам ако бъдат закрити, защото не знаем каква е договорката. А че има договорка е повече от ясно, предвид мирното предаване на властта.
ТРЯБВАТ ПАРИ ЗА ДА СЕ ТУШИРА НАПРЕЖЕНИЕТО
При всички положения новата власт ще се нуждае от пари, за да тушира напрежението. Ако ли не, в тази мултикултурна, раздирана от конфликт земя, където всеки е срещу всеки, ще продължи насилието на религиозна основа. Колкото и да се твърди, че новите „демократични ислямисти“ имат договорки с малцинствата и не ги закачат за момента, едно е ясно – когато ограничиш ресурса и няма достатъчно за всички, малцинствата страдат.
Моето мнение е, че точно това ще се случи на следващия етап. Няма начин след война да няма реваншизъм. Тоест има, но то се нарича НАРОДЕН СЪД. Нещо което много съвременни демократи не харесват, но това е единствения начин да се спре саморазправата в огромни мащаби след война. Прочетете как е било в Руанда, вижте как е било във войната между Етиопия и Еритрея и го наречете както искате, щом определението „Народен съд“ не ви харесва. Но съд ще трябва да има, ако не искаме саморазправи.
РЕСУРСИТЕ
Сирия е на пътя на доста ресурси. Петрол или газ имаме в Иран, Ирак, Кувейт, Саудитска Арабия, Катар, Бахрейн… Ако има има тръби, които да идват в Европа, но да заобикалят Турция, то те тряба да минат през Сирия. Но Турция не иска това. А Русия изобщо не иска да има тръби към Европа. Затова са и техните бази в Сирия, да охраняват маршрута и да гарантират, че няма да има тръби, които да доставят евтин петрол в Европа, който да ги заобикаля. Единствения начин в сегашната обстановка това да остане така е липсата на държава в Сирия, постоянни военни сблъсъци или руските бази да си останат под някаква форма.
Аз не знам каква е договорката и дали техните бази ще останат в сегашната обстановка, но ако се махнат от там, то най-логичното е Русия и Иран да започнат да поддържат и те някаква опозиция или фракция, което е безкрайно по-евтино от поддържането на режим или изграждането на държава.
Личното ми очакване е, че точно това ще се случи.
БЕЖАНЦИТЕ
Гледаме по телевизията колко щастливи са всички от новата власт, но за мен си съм убеден, че това не е така. Виждаме дори, че много сирийци се завръщали в Сирия от Турция. Виждайки как Ердоган търгуваше с Европа посредством бежанците, сега ще е безкрайно щаствлив да изпразни лагерите и да засели териториите граничещи с кюрдите точно с тези бежанци, които години наред хранеше в лагерите и от чиито среди възпита и обучи „демократичните ислямисти“. Да му мислят кюрдите, защото те също се биеха с армията на Асад, докато пък те се биеха с армията на „демократичните ислямисти“. Сега единствената им надежда е САЩ, но въпросът е дали Турция може да плаща и колко, за да държи нещата мирни, защото изобщо не ми се вярва САЩ да плащат и за този конфликт. Най-малко ще се окажат в положението на СССР през 89-та, когато издържаха неефективни режими и съвсем закономерно се разпаднаха.
Европа пък изобщо не я виждам като платец. Те и на Ливан отказаха да плащат вече, а ги чака Украйна, и то в момент, когато германската икономика е в рецесия.
От друга страна Германия и Австрия обявиха официално, че вече няма да приемат бежанци от Сирия. Не ми се вярва и Ердоган да ги приема, защото те вече ще са от другите, а си има правитество в Сирия и тези хора ще са му нужни за а работят, да спират кюрдите и да плащат данъци за поддръжка на новото правителство.
В Европа обаче има маса сирийци и араби. А най-разумното нещо в момента за всеки нормален човек е да защити семейството си. Не мисля, че в следващите години това ще е възможно в Сирия. И дори Турция, Германия и Австрия да не искат повече бежанци от Сирия, саморазправата и насилието тепърва предстоят в онзи район. Както казахме почвата е идеална за Русия и Иран със сравнително малко пари да поддържат новата „демократична опозиция“, само и само да не минават тръби на техни конкуренти, като за всеки изхарчен долар, Турция или ЕС ще трябва да дава по 1000 за да се опита да задържи населението или да изгради държава. Не случайно Асад нареди разпускане на армията и не унищожиха оръжието. Имат да си връщат територията от Израел. Пък като не си я върнат, ще се съобазяват дългосрочно и ще служат на Израел под един или друг начин. Все пак Израел ще владее възвишенията. Ако не беше толкова важно и не им даваха контрол, изобщо нямаше да се опитват да влизат на сирийска територия.
На база всичко казано, аз си правя извода, че големият въпрос в случая е КОЙ ЩЕ ПЛАЩА ЗА СИРИЯ за да продължи да съществува? Не вярвам Турция да може дори и да иска, а Иран и целия останал арабски свят надали ще е много щастлив от разширението на Турция.
Само времето ще покаже какво ще се случи, но през това време доста човешки съдби ще получат нова посока.
Северина Станкева: Предишният ни разговор завърши с темата за разпада, която ми се иска да продължим. Изглежда, че в посткомунистическите държави смъртта на утопията се възприема по особено подчертано автоимунен начин, което би могло да се обясни през статута и историческата съдба на утопичния проект в тях. Това е видимо и във видеоигрите.
В Диско Елизиумахроматичният феномен на Сивотата създава двумилиметрови дупки в тъканта на света. Докато Сивотата е едновременно разделителна тъкан на материята и смесва всичко с всичко – физическите, епистемологическите и лингвистичните качества на нещата по границите ѝ образуват безбрежна ентропична супа, – дупките са предвестници на пълното унищожение. Тъкмо около тях спонтанно се формират духовни институции с апокалиптичен характер – църкви, философски нощни клубове и други.
В първата част на Фростпънк(полска игра, в която играчът приема ролята на лидер на последния град на света, разрушен от безкрайна вулканична зима) – независимо дали оцеляването е постигнато и дори границата на хуманността (буквално има такава) да не е премината – „най-добрият“ край все пак задава въпроса дали всичко си е заслужавало и дали тази граница не се намира всъщност другаде. Доколко това морализаторстване е оправдано, като имайме предвид, че играчът няма какво да направи, за да не премине и невидимата граница, освен може би да спре да играе играта, е друга тема. Във втората част е предприета доста различна, но също толкова съмнителна стратегия относно възможните финали. Имаме един утопичен – всички са щастливи, всичко е наред; друг, в който онези, които не искат мир, са обезвредени; и трети, в който играчът е очевиден диктатор, но мирът пак е постигнат. И в трите случая краят се приема за успешен, с разликата, че в първия и третия успехът изглежда по-голям. Съобщението е едно и също: „Противно на всички шансове, ти успя.“
Какво е отношението на утопията и разпада според вас и в кои игри могат да се открият следите му?
Миглена Николчина: С Еньо Стоянов вече сме обсъждали някои аспекти на тази тема1. Разминаването ни беше в съпоставката между поредиците Метро и Ядрена зима: моята позиция беше, че има принципна разлика между гигантските отломъци на една утопия, сред които се развива действието в Метро, и сантименталните руини на средната класа, сред които си проправяме път в Ядрена зима. Според Еньо по-скоро няма принципна разлика (ако съм го разбрала правилно). Неговата теза е поддържана – извън контекста на видеоигрите – например от Сюзън Бък-Морс в „Мечтани светове и катастрофа. Отмирането на масовата утопия на Изток и Запад“2. Според нея става дума за две аналогични утопии за благоденствие на масите – съветската и американската, – с които е дошло време да се простим. Аз обаче настоявам, отвъд амнезията и носталгиите, върху отгласите от специфичния политически и социален опит на бившите соцстрани. Мисля, че тези отгласи включват повишена чувствителност както към вакуума, който крахът на утопиите оставя след себе си, така и към узурпирането на утопичните проекти от една или друга поредна номенклатура.
Сивотата в Диско Елизиум може да бъде пример за това. Теорията за ерозията на реалността е изложена в играта от една хибридна фигура – ултралибералката (ре)Джойс. Тя е местна жена, зачеркнала някогашната си принадлежност и преминала в лагера на, така да се каже, светлоогъвателите: един от най-забавните персонажи в играта е мегабогаташът, който живее в контейнер, за да не го притесняват просители, и чието лицезрение огъва светлината по силата на „физически закон“, извлечен от романите на Емил Зола. Който е чел Зола, ще разбере. Джойс въплъщава припокриването между ултралибералното корпоративно богатство и морализма на „Моралинтерна“, днешната версия на Комунистическия интернационал. Доколкото ерозиралата реалност е стихията, през която новата номенклатура, Джойс и подобните на нея навигират, ерозията на реалността се оказва скритото опако на Моралинтерна. Тази ерозия е продукт не на старата, а на днешната утопия: продукт на старата утопия е остротата, с която в Диско Елизиум новият утопичен ерзац е съзнаван като вътрешно кух и неспособен да запълни вакуума от предишните сринати проекти.
Кадри от „Метро“ и „Фростпънк“
Eньо Стоянов: Може би било удачно да спрем поглед и на рецептивната страна на въпроса, тъй като тя несъмнено дава и тон на производството в бившите социалистически страни. Първите игри от поредицата Ядрена зима и до днес получават неофициални продължения и модификации от играчи в Източна Европа десетилетия след като западноевропейските играчи са преместили фокуса си върху по-новите заглавия от нея и вероятно дори веднъж не са изигравали изходните заглавия.
Неслучайно този интерес на източноевропейците доведе до поява на заглавия като Атом RPG, който без преувеличение може да се определи като превод на света и системите на първите игри от Ядрена зима в постсъветски апокалиптичен контекст. Герои на мощ и магия 3, също заглавие от края на 90-те, продължава мощно да се играе онлайн днес, при това главно на украински сървъри (преди войната сървърите бяха предимно руски), където по лобитата могат да се открият и много български звучащи прозвища на играчи. И това е при положение, че споменатата поредица си има по-късни продължения (към момента е стигнала до номер 7). Нещо повече, интересът към тази игра се поддържа от времето на създаването ѝ до днес отново с неофициални допълнения, последното от които е от миналата година и е дело на руски разработчици аматьори – явно поне на терена на играенето в мрежа на Герои 3 руснаци и украинци съумяват някак да съжителстват.
Сред тази поредица от примери е уместно да споменем и един български принос – миналата година българското студио Haemimont Games издаде трета част на поредицата Нащърбен съюз. Предишната част също е от края на 90-те и се оказва с „култов“ статус именно в източноевропейски контекст.
Бегло очертаната тук фиксация на вниманието на играчите в бившите соцстрани около заглавия от края на 90-те е закономерна – в тях това е времето на интернет кафенетата, направили за първи път малко по-достъпни видеоигрите в периода на Прехода. Несъмнено всичко това говори за някаква особена носталгия, залозите на която са многоизмерни – от една страна, това е носталгия по обещанието, заложено в самата технология, овъзможностяваща видеоигрите и несъмнено вдъхновила този тласък към онова, за което говореше Северина в предишната част на разговора – т.нар. евровехтории от периода след 2000 г., заглъхнал почти напълно в настоящата ситуация на все по-окрупнена корпоративна форма на производство. Но вероятно тук можем да забележим и по-дълбок корен на тази носталгия – носталгия по утопичните обещания на самия преход в посткомунистическите страни, вещан символно и през самата поява на видеоигрите в тях.
Миглена Николчина: Това е страшно интересно и може да ни отведе към друга тема. За отбелязване е, че през 2008 г. полското студио CD Projekt RED, пожънало огромен международен успех с поредицата Вещерът, създава дъщерна фирма за разпространение, която се казва Good Old Games (GOG), тоест Добрите стари игри. Аз даже мислех, че GOG е създаден по-отдавна, но според Уикипедия годината е тази. По това време първият Вещер току-що е излязъл. Сякаш създателите му още тогава се загрижват за бъдещето на играта си като класика! GOG днес функционира като платформа без вградено управление на дигитални права (DRM) – знак за вярност към утопията за свободно споделяне, която споменаваш. Неотдавна GOG обяви свой нов проект, който са нарекли GOG Preservation Program (Програма за съхраняване на игрите). Един парадоксален ефект на новите технологии е, че продуктите, създадени с тях, се оказват ужасно нетрайни; старите игри бързо стават невъзпроизводими. Новата програма на Добрите стари игри, в духа на собственото си име, си поставя за задача да се бори с бързата смъртност на игрите. В момента има реставрирани над 100 заглавия. Очевидно много играчи ще се зарадват, както се вижда от наблюденията на Еньо, а за изследователите оцеляването на старите игри е абсолютно фундаментално условие. Не виждаме ли в примера с GOG обаче различно отношение не само към утопията, но и към историята?
Еньо Стоянов: Загрижеността около достъпността на стари игри несъмнено е реакция на ситуацията, установила се през последните петнайсетина години на софтуерния пазар. Тя е следствие на това, че дигиталните продукти всъщност вече не са стоки, които можеш да си купиш и да притежаваш (и при нужда, стига да имаш необходимите умения, да приспособиш към нови платформи, операционни системи и пр.), по-скоро корпоративният производител ти издава лиценз за ползване, който може да ти отнеме напълно (нещо, което се случва все по-често), щом сметне, че поддръжката на достъпност на софтуера е вече нерентабилна. Това е по-скоро ефект от липсващи законодателни рамки, които да защитават интересите на потребителите за достъп до софтуер, заплатен от тях.
В момента дори в ЕС се събират подписи за петиция, изискваща правни мерки, които да подсигурят производителите на игри с онлайн достъп да гарантират достъпността на продуктите си след приключване на официалната им поддръжка – в момента корпорациите просто погребват такива игри, за да си спестят разходи по поддръжка на сървърите. Подобни инициативи не са само въпрос на носталгия – тук се намесват въпроси за потребителски права, за интереси от академичен характер и т.н. Носталгичните склонности на посткомунистическите общности от играчи са, струва ми се, по-директно фиксирани около утопичния хоризонт, който самото съществуване на видеоигрите е предвещавало в даден момент и който днешната им индустриална ситуация почти напълно е похабила.
Северина Станкева: Описаното от Еньо показва не само как работи носталгията по добрите стари игри, но и самата добра стара носталгия. Да се каже, че тя е копнеж по миналото, е неточно. Зовът ѝ за завръщане е по-скоро насочен към едно минало бъдеще, т.е. възможността тук е с много по-висок статут от действителността. Реализирането на една или повече възможности неминуемо отдалечава от тази потентна точка на произхода, която предварително е осъдена да бъде пропусната, именно заради порива, който я задвижва. Изглежда, разработчиците на Вещерът се стремят да избегнат това, предпазвайки класическата си игра, преди тя да е станала такава.
Любопитно е, че що се отнася до носталгията по игрите от 90-те, ретротопичните общности от постсоциалистическите държави се оказват с доста голям възрастов диапазон и ако погледнем формално, включват няколко поколения, които, въпреки че донякъде споделят опит в дейността на играенето – компютърни клубове и носители със съмнителен произход, – изпитват носталгия по различни заглавия, макар и пуснати на пазара по същото време. Поколението играчи, което не е и чувало за Герои 3, също помни игри от 90-те, нищо че тогава тепърва се е раждало. Това може да се обясни с обстоятелството, че определени заглавия, най-вече конзолни, стават масово достъпни със закъснение в бившите соцдържави. И в паметта на това следващо поколение игрите на „Дисни“ от края на 90-те например са естествено свързвани с флашигрите или с игрите за браузър от средата на първото десетилетие на ХХI век, макар че, обективно погледнато, между тях има отстояние от около десет години. Херкулес например излиза в същата година като първата част на Ядрена зима, но едва ли ще се намерят много местни играчи, еднакво сантиментални и към двете, или въобще играли и двете. Разбира се, не е за пренебрегване и фактът, че тези игри са ориентирани към различни възрастови публики, но в паметта на западноевропейските общности те все пак могат да се открият една до друга.
Кадри от „Атом RPG“, „Херкулес“ и „Герои 3“
Миглена Николчина: Аз пак ще дръпна разговора към съдържанието на игрите. Поредицата Вещерът, при все че действието се разиграва в измислени царства, обитавани от фантастични раси и чудовища, предлага ясни алегории на полската история. Играта е историческа по същността си, ако и да не е фактологически такава. Амбициозната историческа поредица Кредото на убиеца тръгва от словенски роман: тя се гради на фантастичното допускане, че е възможно да се изживее в плът (така, така – виртуална, де) миналото на предците. Поредицата Метро е дистопия, но в нея има исторически наслагвания, които днешните събития ни карат да преосмислим като исторически фатум. Историческа до степен да претендира за учебно помагало е Идното царство. За Диско Елизиум няма пак да говоря. Ако един от белезите на днешната епоха е, както често се твърди, залиняването на чувството за време и история, тези източноевропейски примери показват изненадващото оцеляване на това чувство във видеоигрите. Тук бих включила и стратегиите на българския разработчик Веселин Ханджиев. Искам да кажа накратко, че археологията на утопията – изненадващо или не – отваря хоризонтите на историята.
Северина Станкева: Миглена каза, че няма да говори повече за Диско Елизиум, но аз не мога да се въздържа от един последен пример, който прекрасно илюстрира връзката утопия–история. Когато играта те хване, че избираш реплики с ляв уклон, се появява Реторика, която ти подшушва, че изглежда, си готов да построиш комунизма отново. Нищо че не се е получавало преди – любовта също не ти се е получавала досега, но значи ли това, че трябва да се откажеш от нея? И въобще, продължава Реторика, провалът е в сърцето на комунизма, ти трябва да го построиш отново именно защото е невъзможно. Ти можеш да се превърнеш в Последния Комунист, който еднолично ще износи на раменете си работническата класа и ще осъществи мечтите ѝ. Ако играчът на това място избере буквално да запретне ръкави и да започне да строи комунизма, Реторика се провиква да влязат фургоните и отрядите за разстрел. Ако играчът каже, че не е искал нищо такова да се случи, отговорът е: вече е твърде късно. Не можеш да направиш омлет, без да счупиш няколко милиона яйца.
Миглена Николчина: Трябва да оценим тази ирония на фона на многократните преки заявления на Курвиц, че е ленинец. Аз не съм стигала до яйцата и въобще не изкарах нито една от четирите политически линии докрай, винаги си правех миш-маш от четирите. Както и – друг проблем на прекалено неигровото ми играене – моето ченге и в трите ми превъртания домисляше мъчително дългата и с множество негативни снижения на способностите му „мисъл“ от мисловния шкаф, наречена „Пустата земя на реалността“ (Waste Land – препратка към Елиът?), накратко, ставаше заклет въздържател. Но не вярвам да има вариант, при който да избегнеш многопластовата ирония, включително политическа – иронията пропива всеки компонент на играта, предметите, дрехите на ченгето, имената, които може да си даде. Например обличането на възможно най-скучния на вид „междуостровен панталон“ (така, предполагам, трябва да се преведе interisolary trousers – светът на Диско Елизиум е островен архипелаг) повишава шанса ти да домислиш „Царството на съвестта“, което е линията на Моралинтерна, и е нужно за успеха на бизнес плана, който предлагаш на светлоогъващия мегабогаташ. Този панталон, така да се каже, олицетворява брака на морализма и монетизацията. Тъй като „междуостровна“ е наречена и валутата в играта, панталонът съответно придобива значение на валутна конвертируемост…
Иронията е съществен аспект и на поредицата Вещерът, но по отношение на днешните готови идеи тази ирония значително намалява с всяка следваща част. От друга страна, CD Projekt RED създават и този съвършено различен (и струва ми се, недостатъчно критически оценен) шедьовър – дистопията Киберпънк. Мегаполисът, където се развива действието, би могъл да бъде на много места, той е изграден с плътност, която засега е ненадмината, но при цялата му киберфутуристичност не си го представям в Полша или въобще в Европа. Този град е едно друго време, но той е и едно друго място, той е не-тук, другаде.
Ще припомня, че през 60-те години в България кипи голям дебат, свързан с литературата – дали голямата литература трябва да е национално или дори регионално локална („котловинна“ е тогавашният термин), или универсална. Цветан Стоянов се включва в този дебат с едно прекрасно кратко есе „По повод духа на мястото“, където в крайна сметка казва, че… ами зависи3. С Вещерът и КиберпънкCD Projekt RED показват, че могат да правят и едното, и другото – и двата пъти успешно достигайки до големи публики. Успехът обаче има цена и тепърва ще видим дали тази цена няма да струва уникалността на полското студио.
1 Вж. (Анти)утопично въображение и трансхуманизация във видеоигрите. – Във: Видеоигрите. Опасната Муза. София: Версус, 2023, с. 382–404.
2 Susan Buck-Morss. Dreamworld and Catastrophe: The Passing of Mass Utopia in East and West. Cambridge, Mass: MIT Press, 2000.
3 Цветан Стоянов. Културата като общение. Т. 1. София: Български писател, 1988, с. 188–193.
В рубриката „Игромислие“ публикуваме разговори, в които се срещат, съпоставят и противопоставят различни гледни точки към многоизмерния, многожанров феномен на видеоигрите – не толкова като електронен спорт, колкото като нов синтез на изкуствата и като ново поле на общуване и социалност.
Given the importance of data in the world today, organizations face the dual challenges of managing large-scale, continuously incoming data while vetting its quality and reliability. The importance of publishing only high-quality data can’t be overstated—it’s the foundation for accurate analytics, reliable machine learning (ML) models, and sound decision-making. Equally crucial is the ability to segregate and audit problematic data, not just for maintaining data integrity, but also for regulatory compliance, error analysis, and potential data recovery.
Apache Iceberg is an open table format that brings atomicity, consistency, isolation, and durability (ACID) transactions to data lakes, streamlining data management. One of its key features is the ability to manage data using branches. Each branch has its own lifecycle, allowing for flexible and efficient data management strategies.
This post explores robust strategies for maintaining data quality when ingesting data into Apache Iceberg tables using AWS Glue Data Quality and Iceberg branches. We discuss two common strategies to verify the quality of published data. We dive deep into the Write-Audit-Publish (WAP) pattern, demonstrating how it works with Apache Iceberg.
Strategy for managing data quality
When it comes to vetting data quality in streaming environments, two prominent strategies emerge: the dead-letter queue (DLQ) approach and the WAP pattern. Each strategy offers unique advantages and considerations.
The DLQ approach – Segregate problematic entries from high-quality data so that only clean data makes it into your primary dataset.
The WAP pattern – Using branches, segregate problematic entries from high-quality data so that only clean data is published in the main branch.
The DLQ approach
The DLQ strategy focuses on efficiently segregating high-quality data from problematic entries so that only clean data makes it into your primary dataset. Here’s how it works:
As data streams in, it passes through a validation process
Valid data is written directly to the table referred by downstream users
Invalid or problematic data is redirected to a separate DLQ for later analysis and potential recovery
The following screenshot shows this flow.
Here are its advantages:
Simplicity – The DLQ approach is straightforward to implement, especially when there is only one writer
Low latency – Valid data is instantly available in the main branch for downstream consumers
Separate processing for invalid data – You can have dedicated jobs to process the DLQ for auditing and recovery purposes.
The DLQ strategy can present significant challenges in complex data environments. With multiple concurrent writers to the same Iceberg table, maintaining consistent DLQ implementation becomes difficult. This issue is compounded when different engines (for example, Spark, Trino, or Python) are used for writes because the DLQ logic may vary between them, making system maintenance more complex. Additionally, storing invalid data separately can lead to management overhead.
Additionally, for low-latency requirements, the processing validation step may introduce additional delays. This creates a challenge in balancing data quality with speed of delivery.
To solve those challenges in a reasonable way, we introduce the WAP pattern in the next section.
The WAP pattern
The WAP pattern implements a three-stage process:
Write – Data is initially written to a staging branch
Audit – Quality checks are performed on the staging branch
Publish – Validated data is merged into the main branch for consumption
The following screenshot shows this flow.
Here are its advantages:
Flexible data latency management – In the WAP pattern, the raw data is ingested to the staging branch without data validation, and then the high-quality data is ingested to the main branch with data validation. With this characteristic, there’s flexibility to achieve urgent, low-latency data handling on the staging branch and achieve high-quality data handling on the main branch.
Unified data quality management – The WAP pattern separates the audit and publish logic from the writer applications. It provides a unified approach to quality management, even with multiple writers or varying data sources. The audit phase can be customized and evolved without affecting the write or publish stages.
The primary challenge of the WAP pattern is the increased latency it introduces. The multistep process inevitably delays data availability for downstream consumers, which may be problematic for near real-time use cases. Furthermore, implementing this pattern requires more sophisticated orchestration compared to the DLQ approach, potentially increasing development time and complexity.
How the WAP pattern works with Iceberg
The following sections explore how the WAP pattern works with Iceberg.
Iceberg’s branching feature
Iceberg offers a branching feature for data lifecycle management, which is particularly useful for efficiently implementing the WAP pattern. The metadata of an Iceberg table stores a history of snapshots. These snapshots, created for each change to the table, are fundamental to concurrent access control and table versioning. Branches are independent histories of snapshots branched from another branch, and each branch can be referred to and updated separately.
When a table is created, it starts with only a main branch, and all transactions are initially written to it. You can create additional branches, such as an audit branch, and configure engines to write to them. Changes on one branch can be fast-forwarded to another branch using Spark’s fast_forward procedure, as shown in the following screenshot.
How to manage Iceberg branches
In this section, we cover the essential operations for managing Iceberg branches using SparkSQL. We’ll demonstrate how to use the branches, specifically, to create a new branch, write to and read from a specific branch, and set a default branch for a Spark session. These operations form the foundation for implementing the WAP pattern with Iceberg.
To create a branch, run the following SparkSQL query:
ALTER TABLE glue_catalog.db.tbl CREATE BRANCH audit
To specify a branch to be updated, use the glue_catalog.<database_name>.<table_name>.branch_<branch_name> syntax:
INSERT INTO glue_catalog.db.tbl.branch_audit VALUES (1, 'a'), (2, 'b');
To specify a branch to be queried, use the glue_catalog.<database_name>.<table_name>.branch_<branch_name> syntax:
SELECT * FROM glue_catalog.db.tbl.branch_audit;
To specify a branch for the entire Spark session scope, set the branch name to the Spark parameter spark.wap.branch. After this parameter is set, all queries will refer to the specified branch without explicit expression:
SET spark.wap.branch = audit

-- audit branch will be updated
INSERT INTO glue_catalog.db.tbl VALUES (3, 'c');
How to implement the WAP pattern with Iceberg branches
Using Iceberg’s branching feature, we can efficiently implement the WAP pattern with a single Iceberg table. Additionally, Iceberg characteristics such as ACID transactions and schema evolution are useful for handling multiple concurrent writers and varying data.
Write – The data ingestion process switches branch from main and it commits updates to the audit branch, instead of the main branch. At this point, these updates aren’t accessible to downstream users who can only access the main branch.
Audit – The audit process runs data quality checks on the data in the audit branch. It specifies which data is clean and ready to be provided.
Publish – The audit process publishes validated data to the main branch with the Iceberg fast_forward procedure, making it available for downstream users.
This flow is shown in the following screenshot.
By implementing the WAP pattern with Iceberg, we can obtain several advantages:
Simplicity – Iceberg branches can express multiple states of a table, such as audit and main, within one table. We can have unified data management even when handling multiple data contexts separately and uniformly.
Handling concurrent writers – Iceberg tables are ACID compliant, so consistent reads and writes are guaranteed even when multiple reader and writer processes run concurrently.
Schema evolution – If there are issues with the data being ingested, its schema may differ from the table definition. Spark supports dynamic schema merging for Iceberg tables. Iceberg tables can flexibly evolve their schema to write data with inconsistent schemas. By configuring the following parameters, when schema changes occur, new columns from the source are added to the target table with NULL values for existing rows. Columns present only in the target have their values set to NULL for new insertions or left unchanged during updates.
SET `spark.sql.iceberg.check-ordering` = false

ALTER TABLE glue_catalog.db.tbl SET TBLPROPERTIES (
    'write.spark.accept-any-schema'='true'
)
df.writeTo("glue_catalog.db.tbl").option("merge-schema","true").append()
As an intermediate wrap-up, the WAP pattern offers a robust approach to managing the balance between data quality and latency. With Iceberg branches, we can implement WAP pattern simply on single Iceberg table with handling concurrent writers and schema evolution.
Example use case
Suppose that a home monitoring system tracks room temperature and humidity. The system captures and sends the data to an Iceberg based data lake built on top of Amazon Simple Storage Service (Amazon S3). The data is visualized using matplotlib for interactive data analysis. For the system, issues such as device malfunctions or network problems can lead to partial or erroneous data being written, resulting in incorrect insights. In many cases, these issues are only detected after the data is sent to the data lake. Additionally, the correctness of such data is generally complicated.
To address these issues, the WAP pattern using Iceberg branches is applied for the system in this post. Through this approach, the incoming room data to the data lake is evaluated for quality before being visualized, and you make sure that only qualified room data is used for further data analysis. With the WAP pattern using the branches, you can achieve effective data management and promote data quality in downstream processes. The solution is demonstrated using AWS Glue Studio notebook, which is a managed Jupyter Notebook for interacting with Apache Spark.
Prerequisites
The following prerequisites are necessary for this use case:
An active AWS Account that provides access to AWS Glue, Amazon S3 and AWS CloudFormation.
Complete the following steps to deploy the resources.
Choose Launch stack.
For the Parameters, IcebergDatabaseName is set by default. You can also change the default value. Then, choose Next.
Choose Next.
Choose I acknowledge that AWS CloudFormation might create IAM resources with custom names.
Choose Submit.
After the stack creation is complete, check the Outputs The resource values are used in the following sections.
Next, configure the Iceberg JAR files to the session to use the Iceberg branch feature. Complete the following steps:
Select the following JAR files from the Iceberg releases page and download these JAR files on your local machine:
1.6.1 Spark 3.3_with Scala 2.12 runtime Jar
1.6.1 aws-bundle Jar
Open the Amazon S3 console and select the S3 bucket you created through the CloudFormation stack. The S3 bucket name can be found on the CloudFormation Outputs tab.
Choose Create folder and create the jars path in the S3 bucket.
Upload the two downloaded JAR files to s3://<IcebergS3Bucket>/jars/ from the S3 console.
Upload a Jupyter Notebook on AWS Glue Studio
After launching the CloudFormation stack, you create an AWS Glue Studio notebook to use Iceberg with AWS Glue. Complete the following steps.
Select Upload Notebook, choose Choose file, and upload the notebook you downloaded.
Select the IAM role name, such as IcebergWAPGlueJobRole, that you created through the CloudFormation stack. Then, choose Create notebook.
For Job name at the left top of the page, enter iceberg_wap.
Choose Save.
Configure Iceberg branches
Start by creating an Iceberg table that contains a room temperature and humidity dataset. After creating the Iceberg table, create branches that are used for performing the WAP practice. Complete the following steps:
On the Jupyter Notebook that you created in Upload a Jupyter Notebook on AWS Glue Studio, run the following cell to use Iceberg with Glue. %additional_python_modules pandas==2.2 is used to visualize the temperature and humidity data in the notebook with pandas. Before running the cell, replace <IcebergS3Bucket> with the S3 bucket name where you uploaded the Iceberg JAR files.
Initialize the SparkSession by running the following cell. The first three settings, starting with spark.sql, are required to use Iceberg with Glue. The default catalog name is set to glue_catalog using spark.sql.defaultCatalog. The configuration spark.sql.execution.arrow.pyspark.enabled is set to true and is used for data visualization with pandas.
After the session is created (the notification Session <Session Id> has been created. will be displayed in the notebook), run the following commands to copy the temperature and humidity dataset to the S3 bucket you created through the CloudFormation stack. Before running the cell, replace <IcebergS3Bucket> with the name of the S3 bucket for Iceberg, which you can find on the CloudFormation Outputs tab.
Configure the data source bucket name and path (DATA_SRC), Iceberg data warehouse path (ICEBERG_LOC), and database and table names for an Iceberg table (DB_TBL). Replace <IcebergS3Bucket> with the S3 bucket from the CloudFormation Outputs tab.
Read the dataset and create the Iceberg table with the dataset using the Create Table As Select (CTAS) query.
Run the following code to display the temperature and humidity data for each room in the Iceberg table. Pandas and matplotlib are used to visualize the data for each room. The data from 10:05 to 10:30 is displayed in the notebook, as shown in the following screenshot, with each room showing approximately 25°C for temperature (displayed as the blue line) and 52% for humidity (displayed as the orange line).
import matplotlib.pyplot as plt
import pandas as pd

CONF = [
    {'room_type': 'myroom', 'cols':['current_temperature', 'current_humidity']},
    {'room_type': 'living', 'cols':['current_temperature', 'current_humidity']},
    {'room_type': 'kitchen', 'cols':['current_temperature', 'current_humidity']}
]

fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL} WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 60)
    plt.yticks([tick for tick in range(10, 60, 10)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt
You create Iceberg branches by running the following queries before writing data into the Iceberg table. You can create an Iceberg branch by the ALTER TABLE db.table CREATE BRANCH <branch_name> query.
ALTER TABLE iceberg_wap_db.room_data CREATE BRANCH stg
ALTER TABLE iceberg_wap_db.room_data CREATE BRANCH audit
Now, you’re ready to build the WAP pattern with Iceberg.
Build WAP pattern with Iceberg
Use the Iceberg branches created earlier to implement the WAP pattern. You start writing the newly incoming temperature and humidity data including erroneous values to the stg branch in the Iceberg table.
Write phase: Write incoming data into the Iceberg stg branch
To write the incoming data into the stg branch in the Iceberg table, complete the following steps:
Run the following cell and write the data into Iceberg table.
After the records are written, run the following code to visualize the current temperature and humidity data in the stg On the following screenshot, notice that new data was added after 10:30. The output shows incorrect readings, such as around 100°C for temperature between 10:35 and 10:52 in the living room.
fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room_stg = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL}.branch_stg WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room_stg.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 110)
    plt.yticks([tick for tick in range(10, 110, 30)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt
The new temperature data including erroneous records was written to the stg branch. This data isn’t visible to the downstream side because it hasn’t been published to the main branch. Next, you evaluate the data quality in the stg branch.
Audit phase: Evaluate the data quality in the stg branch
In this phase, you evaluate the quality of the temperature and humidity data in the stg branch using AWS Glue Data Quality. Then, the data that doesn’t meet the criteria is filtered out based on the data quality rules, and the qualified data is used to update the latest snapshot in the audit branch. Start with the data quality evaluation:
Run the following code to evaluate the current data quality using AWS Glue Data Quality. The evaluation rule is defined in DQ_RULESET, where the normal temperature range is set between −10 and 50°C based on the device specifications. Any values out of this range are considered erroneous in this scenario.
from awsglue.context import GlueContext
from awsglue.transforms import SelectFromCollection
from awsglue.dynamicframe import DynamicFrame
from awsgluedq.transforms import EvaluateDataQuality
DQ_RULESET = """Rules = [ ColumnValues "current_temperature" between -10 and 50 ]"""


dyf = DynamicFrame.fromDF(
    dataframe=spark.sql(f"SELECT * FROM {DB_TBL}.branch_stg"),
    glue_ctx=GlueContext(spark.sparkContext),
    name='dyf')

dyfc_eval_dq = EvaluateDataQuality().process_rows(
    frame=dyf,
    ruleset=DQ_RULESET,
    publishing_options={
        "dataQualityEvaluationContext": "dyfc_eval_dq",
        "enableDataQualityCloudWatchMetrics": False,
        "enableDataQualityResultsPublishing": False,
    },
    additional_options={"performanceTuning.caching": "CACHE_NOTHING"},
)

# Show DQ results
dyfc_rule_outcomes = SelectFromCollection.apply(
    dfc=dyfc_eval_dq,
    key="ruleOutcomes")
dyfc_rule_outcomes.toDF().select('Outcome', 'FailureReason').show(truncate=False)
The output shows the result of the evaluation. It displays Failed because some temperature data, such as 105°C, is out of the normal temperature range of −10 to 50°C.
+-------+------------------------------------------------------+
|Outcome|FailureReason                                         |
+-------+------------------------------------------------------+
|Failed |Value: 105.0 does not meet the constraint requirement!|
+-------+------------------------------------------------------+
After the evaluation, filter out the incorrect temperature data in the stg branch, then update the latest snapshot in the audit branch with the valid temperature data.
Through the data quality evaluation, the audit branch in the Iceberg table now contains the valid data, which is ready for downstream use.
Publish phase: Publish the valid data to the downstream side
To publish the valid data in the audit branch to main, complete the following steps:
Run the fast_forward Iceberg procedure to publish the valid data in the audit branch to the downstream side.
After the procedure is complete, review the published data by querying the main branch in the Iceberg table to simulate the query from the downstream side.
fig, axes = plt.subplots(nrows=3, ncols=1, sharex=True, sharey=True)
for ax, conf in zip(axes.ravel(), CONF):
    df_room_main = spark.sql(f"""
        SELECT current_time, current_temperature, current_humidity, room_type
        FROM {DB_TBL} WHERE room_type = '{conf['room_type']}'
        ORDER BY current_time ASC
        """)
    pdf = df_room_main.toPandas()
    pdf.set_index(pdf['current_time'], inplace=True)
    plt.xlabel('time')
    plt.ylabel('temperature/humidity')
    plt.ylim(10, 60)
    plt.yticks([tick for tick in range(10, 60, 10)])
    pdf[conf['cols']].plot.line(ax=ax, grid=True, figsize=(8, 6), title=conf['room_type'], legend=False, marker=".", markersize=2, linewidth=0)

plt.legend(['temperature', 'humidity'], loc='center', bbox_to_anchor=(0, 1, 1, 5.5), ncol=2)

%matplot plt
The query result shows only the valid temperature and humidity data that has passed the data quality evaluation.
In this scenario, you successfully managed data quality by applying the WAP pattern with Iceberg branches. The room temperature and humidity data, including any erroneous records, was first written to the staging branch for quality evaluation. This approach prevented erroneous data from being visualized and leading to incorrect insights. After the data was validated by AWS Glue Data Quality, only valid data was published to the main branch and visualized in the notebook. Using the WAP pattern with Iceberg branches, you can make sure that only validated data is passed to the downstream side for further analysis.
Clean up resources
To clean up the resources, complete the following steps:
On the Amazon S3 console, select the S3 bucket aws-glue-assets-<ACCOUNT_ID>-<REGION> where the Notebook file (iceberg_wap.ipynb) is stored. Delete the Notebook file located in the notebook path.
Select the S3 bucket you created through the CloudFormation template. You can obtain the bucket name from IcebergS3Bucket key on the CloudFormation Outputs tab. After selecting the bucket, choose Empty to delete all objects.
After you confirm the bucket is empty, delete the CloudFormation stack iceberg-wap-baseline-resources.
Conclusion
In this post, we explored common strategies for maintaining data quality when ingesting data into Apache Iceberg tables. The step-by-step instructions demonstrated how to implement the WAP pattern with Iceberg branches. For use cases requiring data quality validation, the WAP pattern provides the flexibility to manage data latency even with concurrent writer applications without impacting downstream applications.
About the Authors
Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.
Sotaro Hikita is a Solutions Architect. He supports customers in a wide range of industries, especially the financial industry, to build better solutions. He is particularly passionate about big data technologies and open source software.
Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.
In today’s data-driven world, tracking and analyzing changes over time has become essential. As organizations process vast amounts of data, maintaining an accurate historical record is crucial. History management in data systems is fundamental for compliance, business intelligence, data quality, and time-based analysis. It enables organizations to maintain audit trails, perform trend analysis, identify data quality issues, and conduct point-in-time reporting. When combined with Change Data Capture (CDC), which identifies and captures database changes, history management becomes even more potent.
Common use cases for historical record management in CDC scenarios span various domains. In customer relationship management, it tracks changes in customer information over time. Financial systems use it for maintaining accurate transaction and balance histories. Inventory management benefits from historical data for analyzing sales patterns and optimizing stock levels. HR systems use it to track employee information changes. In fraud detection, historical data helps identify anomalous patterns in transactions or user behaviors.
This post will explore how to implement these functionalities using Apache Iceberg, focusing on Slowly Changing Dimensions (SCD) Type-2. This method creates new records for each data change while preserving old ones, thus maintaining a full history. By the end, you’ll understand how to use Apache Iceberg to manage historical records effectively on a typical CDC architecture.
Historical record lookup
How can we retrieve the history of given records? This is a fundamental question in data management, especially when dealing with systems that need to track changes over time. Let’s explore this concept with a practical example.
Consider a product (Heater) in an ecommerce database:
product_id
product_name
price
00001
Heater
250
Now, let’s say we update the price of this product from 250 to 500. After some time, we want to retrieve the price history of this heater. In a traditional database setup, this task could be challenging, especially if we haven’t explicitly designed our system to track historical changes.
This is where the concept of historical record lookup becomes crucial. We need a system that not only stores the current state of our data but also maintains a log of all changes made to each record over time. This allows us to answer questions like:
What was the price of the heater at a specific point in time?
How many times has the price changed, and when did these changes occur?
What was the price trend of the heater over the past year?
Implementing such a system can be complex, requiring careful consideration of data storage, retrieval mechanisms, and query optimization. This is where Apache Iceberg comes into play, offering a feature known as the change log view.
The change log view in Apache Iceberg provides a view of all changes made to a table over time, making it straightforward to query and analyze the history of any record. With change log view, we can easily track insertions, updates, and deletions, giving us a complete picture of how our data has evolved.
For our heater example, Iceberg’s change log view would allow us to effortlessly retrieve a timeline of all price changes, complete with timestamps and other relevant metadata, as shown in the following table.
product_id
product_name
price
_change_type
00001
Heater
250
INSERT
00001
Heater
250
UPDATE_BEFORE
00001
Heater
500
UPDATE_AFTER
This capability not only simplifies historical analysis but also opens possibilities for advanced time-based analytics, auditing, and data governance.
Historical table lookup with SCD Type-2
SCD Type-2 is a key concept in data warehousing and historical data management and is particularly relevant to Change Data Capture (CDC) scenarios. SCD Type-2 creates new rows for changed data instead of overwriting existing records, allowing for comprehensive tracking of changes over time.
SCD Type-2 requires additional fields such as effective_start_date, effective_end_date, and current_flag to manage historical records. This approach has been widely used in data warehouses to track changes in various dimensions such as customer information, product details, and employee data. In the example of the previous section, here’s what the SCD Type-2 looks like assuming the update operation is performed on December 11, 2024.
product_id
product_name
price
effective_start_date
effective_end_date
current_flag
00001
Heater
250
2024-12-10
2024-12-11
FALSE
00001
Heater
500
2024-12-11
NULL
TRUE
SCD Type-2 is particularly valuable in CDC use cases, where capturing all data changes over time is crucial. It enables point-in-time analysis, provides detailed audit trails, aids in data quality management, and helps meet compliance requirements by preserving historical data.
In traditional implementations on data warehouses, SCD Type-2 requires its specific handling in all INSERT, UPDATE, and DELETE operations that affect those additional columns. For example, to update the price of the product, you need to run the following query.
UPDATE product SET effective_end_date = '2024-12-11', current_flag = false
WHERE product_id = '00001' AND current_flag = true;

INSERT INTO product (product_id, product_name, price, effective_start_date, effective_end_date, current_flag)
VALUES ('00001', 'Heater', 500, '2024-12-11', NULL, true);
For modern data lakes, we propose a new approach to implement SCD Type-2. With Iceberg, you can create a dedicated view of SCD Type-2 on top of the change log view, eliminating the need to implement specific handling to make changes on SCD Type-2 tables. With this approach, you can keep managing Iceberg tables without complexity considering SCD Type-2 specification. Anytime when you need SCD Type-2 snapshot of your Iceberg table, you can create the corresponding representation. This approach combines the power of Iceberg’s efficient data management with the historical tracking capabilities of SCD Type-2. By using the change log view, Iceberg can dynamically generate the SCD Type-2 structure without the overhead of maintaining additional tables or manually managing effective dates and flags.
This streamlined method not only makes the implementation of SCD Type-2 more straightforward, but also offers improved performance and scalability for handling large volumes of historical data in CDC scenarios. It represents a significant advancement in historical data management, merging traditional data warehousing concepts with modern big data capabilities.
As we delve deeper into Iceberg’s features, we’ll explore how this approach can be implemented, showcasing the efficiency and flexibility it brings to historical data analysis and CDC processes.
Prerequisites
The following prerequisites are required for the use cases:
Complete the following steps to deploy the resources.
Choose Launch stack
For the parameters, IcebergDatabaseName is set by default. You can change the default value. Then, choose Next.
Choose Next
Choose I acknowledge that AWS CloudFormation might create IAM resources with custom names.
Choose Submit.
After the stack creation is complete, check the Outputs tab and make a note of the resource values, which are used in the following sections.
Next, configure the Iceberg JAR files to the session to use the Iceberg change log view feature. Complete the following steps.
Select the following JAR files from the Iceberg releases page and download these JAR files on your local machine:
1.6.1 Spark 3.3_with Scala 2.12 runtime Jar.
1.6.1 aws-bundle Jar.
Open the Amazon S3 console and select the S3 bucket you created using the CloudFormation stack. The S3 bucket name can be found on the CloudFormation Outputs tab.
Choose Create folder and create the jars path in the S3 bucket.
Upload the two downloaded JAR files on s3://<IcebergS3Bucket>/jars/ from the S3 console.
Upload a Jupyter Notebook on AWS Glue Studio
After launching the CloudFormation stack, create an AWS Glue Studio notebook to use Iceberg with AWS Glue.
Select Upload Notebook, choose Choose file and upload the Notebook you downloaded.
Select the IAM role name such as IcebergHistoryGlueJobRole that you created using the CloudFormation template. Then, choose Create notebook.
For Job name at the left top of the page, enter iceberg_history.
Choose Save.
Create an Iceberg table
To create an Iceberg table using a product dataset, complete the following steps.
On the Jupyter Notebook that you created in Upload a Jupyter Notebook on AWS Glue Studio, run the following cell to use Iceberg with AWS Glue. Before running the cell, replace <IcebergS3Bucket> with the S3 bucket name where you uploaded the Iceberg JAR files.
Initialize the SparkSession with Iceberg settings.
Configure database and table names for an Iceberg table (DB_TBL) and data warehouse path (ICEBERG_LOC). Replace <IcebergS3Bucket> with the S3 bucket from the CloudFormation Outputs tab.
Run the following code to create the Iceberg table using the Spark DataFrame based on the product dataset.
from pyspark.sql import Row
import time
ut = time.time()
product = [
    {'product_id': '00001', 'product_name': 'Heater', 'price': 250, 'category': 'Electronics', 'updated_at': ut},
    {'product_id': '00002', 'product_name': 'Thermostat', 'price': 400, 'category': 'Electronics', 'updated_at': ut},
    {'product_id': '00003', 'product_name': 'Television', 'price': 600, 'category': 'Electronics', 'updated_at': ut},
    {'product_id': '00004', 'product_name': 'Blender', 'price': 100, 'category': 'Electronics', 'updated_at': ut},
    {'product_id': '00005', 'product_name': 'USB charger', 'price': 50, 'category': 'Electronics', 'updated_at': ut}
]
df_products = spark.createDataFrame(Row(**x) for x in product)
df_products.createOrReplaceTempView('tmp')

spark.sql(f"""
CREATE TABLE {DB_TBL} USING iceberg LOCATION '{ICEBERG_LOC}'
AS SELECT * FROM tmp
""")
After creating the Iceberg table, run SELECT * FROM iceberg_history_db.products ORDER BY product_id to show the product data in the Iceberg table. Currently the following five products are stored in the Iceberg table.
Next, look up the historical changes for a product using Iceberg’s change log view feature.
Implement historical record lookup with Iceberg’s change log view
Suppose that there’s a source table whose table records are replicated to the Iceberg table through a Change Data Capture (CDC) process. When the records in the source table are updated, these changes are then mirrored in the Iceberg table. In this section, you look up the history of a given record for such a system to capture the history of product updates. For example, the following updates occur in the source table. Through the CDC process, these changes are applied to the Iceberg table.
Upsert (update and insert) the two records:
The price of Heater (product_id: 00001) is updated from 250 to 500.
A new product Chair (product_id: 00006) is added.
Television (product_id: 00003) is deleted.
To simulate the CDC workflow, you manually apply these changes to the Iceberg table in the notebook.
Use the MERGE INTO query to upsert records. If an input record in the Spark DataFrame has the same product_id as an existing record, the existing record is updated. If no matching product_id is found, the input record is inserted into the Iceberg table.
Delete Television from the Iceberg table by running the DELETE query.
DELETE FROM iceberg_history_db.products WHERE product_id = '00003'
Then, run SELECT * FROM iceberg_history_db.products ORDER BY product_id to show the product data in the Iceberg table. You can confirm that the price of Heater is updated to 500, Chair is added and Television is deleted.
For the Iceberg table, where changes from the source table are replicated, you can track the record changes using Iceberg’s change log view. To start, you first create a change log view from the Iceberg table.
Run the create_changelog_view Iceberg procedure to create a change log view.
Run the following query to retrieve the historical changes for Heater.
SELECT product_id, product_name, price, category, updated_at, _change_type
FROM products_clv WHERE product_id = '00001'
ORDER BY _change_ordinal, _change_type DESC
The query result shows the historical changes to Heater. You can confirm that the price of Heater was updated from 250 to 500 from the output.
Using Iceberg’s change log view, you can obtain the history of a given record directly from the Iceberg table’s history, without needing to create a separate table for managing record history. Next, you implement Slowly Changing Dimension (SCD) Type-2 using the change log view.
Implement SCD Type-2 with Iceberg’s change log view
The SCD Type-2 based table retains the full history of record changes and it can be used in multiple cases such as historical tracking, point-in-time analysis, regulatory compliance, and so on. In this section, you implement SCD Type-2 using the change log view (products_clv) that was created in the previous section. The change log view has a schema that’s similar to the schema defined in the SCD Type-2 specifications. For this change log view, you add effective_start, effective_end, and is_current columns. To add these columns and then implement SCD Type-2, complete the following steps.
Run the following query to implement SCD Type-2. In the WITH AS (...) section of the query, the change log view is merged with the Iceberg table snapshots using the snapshot_id key to include the commit time for each record change. You can obtain the table snapshots by querying for db.table.snapshots. The other part in the query identifies both current and non-current entries by comparing the commit times for each product. It then sets the effective time for each product, and marks whether a product is current or not based on the effective time and the change type from the change log view.
WITH clv_snapshots AS (
    SELECT
        clv.*,
        s.snapshot_id,
        s.committed_at,
        s.committed_at as effective_start
    FROM products_clv clv
    JOIN iceberg_history_db.products.snapshots s
    ON clv._commit_snapshot_id = s.snapshot_id
)
SELECT
    product_id,
    product_name,
    price,
    category,
    updated_at,
    effective_start,
    CASE
        WHEN effective_start != l_part_committed_at
            OR _change_type = 'UPDATE_BEFORE' THEN l_part_committed_at
        ELSE CAST(null as timestamp)
    END as effective_end,
    CASE
        WHEN effective_start != l_part_committed_at
            OR _change_type = 'UPDATE_BEFORE'
            OR _change_type = 'DELETE' THEN CAST(false as boolean)
        ELSE CAST(true as boolean)
    END as is_current
FROM (SELECT *, MAX(committed_at) OVER (PARTITION BY product_id, updated_at) as l_part_committed_at FROM clv_snapshots)
WHERE _change_type != 'UPDATE_BEFORE'
ORDER BY product_id,  _change_ordinal
The query result shows the SCD Type-2 based schema and records.
After the query result is displayed, this SCD Type-2 based table is stored as scdt2 to allow access for further analysis.
SCD Type-2 is useful for many use cases. To explore how this SCD Type-2 implementation can be used to track the history of table records, run the following example queries.
Run the following query to retrieve deleted or updated records in a specific period. This query captures which records were changed during that timeframe, allowing you to audit changes for further use-cases such as trend analysis, regulatory compliance checks, and so on. Before running the query, replace <START_DATETIME> and <END_DATETIME> with specific time ranges such as 2024-10-24 17:18:00 and 2024-10-24 17:20:00.
SELECT product_id, product_name, price, category, updated_at, effective_start, effective_end, is_current
FROM scdt2 WHERE product_id IN ( SELECT product_id FROM scdt2
WHERE (_change_type = 'DELETE' or _change_type = 'UPDATE_AFTER')
AND effective_start BETWEEN '<START_DATETIME>' AND '<END_DATETIME>')
ORDER BY product_id, effective_start
The query result shows the deleted and updated records in the specified period. You can confirm that the price of Heater was updated and Television was deleted from the table.
As another example, run the following query to retrieve the latest records at a specific point in time from the SCD Type-2 table by filtering with is_current = true for current data reporting.
SELECT product_id, product_name, price, category, updated_at
FROM scdt2 WHERE is_current = true ORDER BY product_id
The query result shows the current table records, reflecting the updated price of Heater, the deletion of Television, and the addition of Chair after the initial records.
You have now successfully implemented SCD Type-2 using the change log view. This SCD Type-2 implementation allows you to track the history of table records. For example, you can use it to search for deleted or updated products such as Heater and Chair in a specific period. Additionally, you can retrieve the current table records by querying the SCD Type-2 table with is_current = true. Using Iceberg’s change log view enables you to implement SCD Type-2 without making any changes to the Iceberg table itself. It also eliminates the need for creating or managing an additional table for SCD Type-2.
Clean up
To clean up the resources used in this post, complete the following steps:
Select the S3 bucket aws-glue-assets-<ACCOUNT_ID>-<REGION> where the Notebook file (iceberg_history.ipynb) is stored. Delete the Notebook file that’s in the notebook path.
Select the S3 bucket you created using the CloudFormation template. You can obtain the bucket name from IcebergS3Bucket key on the CloudFormation Outputs tab. After selecting the bucket, choose Empty to delete all objects
After you confirm the bucket is empty, delete the CloudFormation stack iceberg-history-baseline-resources.
Considerations
Here are important considerations:
The change log view does not lose any historical record changes even when following operations are performed:
The change log view is not supported in MoR tables.
Conclusion
In this post, we have explored how to look up the history of records and tables using Apache Iceberg. The instruction demonstrated how to use change log view to look up the history of the records, and also the history of the tables with SCD Type-2. With this method, you can manage the history of records and tables without extra effort.
About the Authors
Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.
Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.
When the Fedora Engineering Steering Council (FESCo) is up for election, the project posts
interviews of the candidates in order to help Fedora contributors make an informed choice. This
year, the candidates are
Zbigniew Jędrzejewski-Szmek,
Tomáš Hrčka,
Josh Stone,
David Cantrell,
Fabio Alessandro Locati, and
Kevin Fenzi.
All of them except for Locati are current members of the steering council.
Voting is open until December 20.
In 2019, the Python community had a
lengthy discussion about changing the rules (that some find counterintuitive) on
using break, continue, or return statements in finally blocks. These are all ways of jumping out of a finally
block, which can interrupt the handling of a raised exception.
At the time, the Python developers chose not to change
things, because the consensus was that the existing behavior was not a problem. Now, after a
report put together by Irit Katriel, the project is once again considering
changing the language.
The OpenWrt project has issued an
advisory regarding a vulnerability found in its Attended Sysupgrade
Server that could allow compromised packages to be installed on a router by
an attacker. No official OpenWrt images were affected, and the
vulnerability is not known to be exploited, but users who have installed
images created with an instance of this server are recommended to
reinstall.
For a detailed description of how the exploit works, see this
blog post.
Then, as the hash collision occurred, the server returns the
overwritten build artifact to the legitimate request that requests
the following packages. […]
By abusing this, an attacker could force the user to upgrade to the
malicious firmware, which could lead to the compromise of the
device.
The 6.13-rc2 kernel prepatch is out for
testing. “The diffstat looks a bit unusual with 80%+ drivers, and a lot of it
one-liners, but that’s actually just because of a couple of automated
scripts that got run after -rc1 for some cleanups. Nothing
particularly interesting, but it makes for a lot of noise in the diff.”
One of those scripts was the EXPORT_SYMBOL_NS() change (to make it
use a quoted string for the namespace name) described in this article.
The 2024 Cloudflare Radar Year in Review is our fifth annual review of Internet trends and patterns observed throughout the year at both a global and country/region level across a variety of metrics. In this year’s review, we have added several new traffic, adoption, connectivity, and email security metrics, as well as the ability to do year-over-year and geographic comparisons for selected metrics.
Below, we present a summary of key findings, and then explore them in more detail in subsequent sections.
Google maintained its position as the most popular Internet service overall. OpenAI remained at the top of the Generative AI category. Binance remained at the top of the Cryptocurrency category. WhatsApp remained the top Messaging platform, and Facebook remained the top Social Media site. 🔗
Global traffic from Starlink grew 3.3x in 2024, in line with last year’s growth rate. After initiating service in Malawi in July 2023, Starlink traffic from that country grew 38x in 2024. As Starlink added new markets, we saw traffic grow rapidly in those locations. 🔗
Googlebot, Google’s web crawler, was responsible for the highest volume of request traffic to Cloudflare in 2024, as it retrieved content from millions of Cloudflare customer sites for search indexing. 🔗
Traffic from ByteDance’s AI crawler (Bytespider) gradually declined over the course of 2024. Anthropic’s AI crawler (ClaudeBot) first started showing signs of ongoing crawling activity in April, then declined after an initial peak in May & June. 🔗
13.0% of TLS 1.3 traffic is using post-quantum encryption. 🔗
Adoption & Usage
Globally, nearly one-third of mobile device traffic was from Apple iOS devices. Android had a >90% share of mobile device traffic in 29 countries/regions; peak iOS mobile device traffic share was over 60% in eight countries/regions. 🔗
Globally, nearly half of web requests used HTTP/2, with 20.5% using HTTP/3. Usage of both versions was up slightly from 2023. 🔗
React, PHP, and jQuery were among the most popular technologies used to build websites, while HubSpot, Google, and WordPress were among the most popular vendors of supporting services and platforms. 🔗
Go surpassed NodeJS as the most popular language used for making automated API requests. 🔗
Google is far and away the most popular search engine globally, across all platforms. On mobile devices and operating systems, Baidu is a distant second. Bing is a distant second across desktop and Windows devices, with DuckDuckGo second most popular on macOS. Shares vary by platform and country/region. 🔗
Google Chrome is far and away the most popular browser overall. While this is also true on macOS devices, Safari usage is well ahead of Chrome on iOS devices. On Windows, Edge is the second most popular browser as it comes preinstalled and is the initial default. 🔗
Connectivity
225 major Internet disruptions were observed globally in 2024, with many due to government-directed regional and national shutdowns of Internet connectivity. Cable cuts and power outages were also leading causes. 🔗
Aggregated across 2024, 28.5% of IPv6-capable requests were made over IPv6. India and Malaysia were the strongest countries, at 68.9% and 59.6% IPv6 adoption respectively. 🔗
The top 10 countries ranked by Internet speed all had average download speeds above 200 Mbps. Spain was consistently among the top locations across the measured Internet quality metrics. 🔗
41.3% of global traffic comes from mobile devices. In nearly 100 countries/regions, the majority of traffic comes from mobile devices. 🔗
20.7% of TCP connections are unexpectedly terminated before any useful data can be exchanged. 🔗
Security
6.5% of global traffic was mitigated by Cloudflare’s systems as being potentially malicious or for customer-defined reasons. In the United States, the share of mitigated traffic grew to 5.1%, while in South Korea, it dropped slightly to 8.1%. In 44 countries/regions, over 10% of traffic was mitigated. 🔗
The United States was responsible for over a third of global bot traffic. Amazon Web Services was responsible for 12.7% of global bot traffic, and 7.8% came from Google. 🔗
Globally, Gambling/Games was the most attacked industry, slightly ahead of 2023’s most targeted industry, Finance. 🔗
Log4j, a vulnerability discovered in 2021, remains a persistent threat and was actively targeted throughout 2024. 🔗
Routing security, measured as the share of RPKI valid routes and the share of covered IP address space, continued to improve globally throughout 2024. We saw a 4.7% increase in RPKI valid IPv4 address space in 2024, and a 6.4% increase in RPKI valid routes in 2024. 🔗
Email Security
An average of 4.3% of emails were determined to be malicious in 2024, although this figure was likely influenced by spikes observed in March, April, and May. Deceptive links and identity deception were the two most common types of threats found in malicious email messages. 🔗
Over 99% of the email messages processed by Cloudflare Email Security from the .bar, .rest, and .uno top level domains (TLDs) were found to be either spam or malicious in nature. 🔗
Introduction
Over the last four years (2020, 2021, 2022, 2023), we have aggregated perspectives from Cloudflare Radar into an annual Year In Review, illustrating the Internet’s patterns across multiple areas over the course of that year. The Cloudflare Radar 2024 Year In Review microsite continues that tradition, featuring interactive charts, graphs, and maps you can use to explore and compare notable Internet trends observed throughout this past year.
Cloudflare’s network currently spans more than 330 cities in over 120 countries/regions, serving an average of over 63 million HTTP(S) requests per second for millions of Internet properties, in addition to handling over 42 million DNS requests per second on average. The resulting data generated by this usage, combined with data from other complementary Cloudflare tools, enables Radar to provide unique near-real time perspectives on the patterns and trends around security, traffic, performance, and usage that we observe across the Internet.
The 2024 Year In Review is organized into five sections: Traffic, Adoption & Usage, Connectivity, Security, and Email Security and covers the period from January 1 to December 1, 2024. We have incorporated several new metrics this year, including AI bot & crawler traffic, search engine and browser market share, connection tampering, and “most dangerous” top level domains (TLDs). To ensure consistency, we have kept underlying methodologies consistent with previous years’ calculations. Trends for 200 countries/regions are available on the microsite; smaller or less populated locations are excluded due to insufficient data. Some metrics are only shown worldwide, and are not displayed if a country/region is selected.
Below, we provide an overview of the content contained within the major Year In Review sections (Traffic, Adoption & Usage, Connectivity, Security, and Email Security), along with notable observations and key findings. In addition, we have also published a companion blog post that specifically explores trends seen across Top Internet Services.
The key findings and associated discussion within this post only provide a high-level perspective on the unique insights that can be found in the Year in Review microsite. Visit the microsite to explore the various datasets and metrics in more detail, including trends seen in your country/region, how these trends have changed as compared to 2023, and how they compare to other countries/regions of interest. Surveying the Internet from this vantage point provides insights that can inform decisions on everything from an organization’s security posture and IT priorities to product development and strategy.
Traffic trends
Global Internet traffic grew 17.2% in 2024.
An inflection point for Internet traffic arguably occurred thirty years ago. The World Wide Web went mainstream in 1994, thanks to the late 1993 release of the NCSA Mosaic browser for multiple popular operating systems, which included support for embedded images. In turn, “heavier” (in contrast to text-based) Internet content became the norm, and coupled with the growth in consumption through popular online services and the emerging consumer ISP industry, Internet traffic began to rapidly increase, and that trend has continued to the present.
To determine the traffic trends over time for the Year in Review, we use the average daily traffic volume (excluding bot traffic) over the second full calendar week (January 8-15) of 2024 as our baseline. (The second calendar week is used to allow time for people to get back into their “normal” school and work routines after the winter holidays and New Year’s Day. The percent change shown in the traffic trends chart is calculated relative to the baseline value — it does not represent absolute traffic volume for a country/region. The trend line represents a seven-day trailing average, which is used to smooth the sharp changes seen with data at a daily granularity. To compare 2024’s traffic trends with 2023 data and/or other locations, click the “Compare” icon at the upper right of the graph.
Throughout the first half of 2024, worldwide Internet traffic growth appeared to be fairly limited, within a percent or two on either side of the baseline value through mid-August. However, at that time growth clearly began to accelerate, climbing consistently through the end of November, growing 17.2% for the year. This trend is similar to those also seen in 2023 and 2022, as we discussed in the 2023 Year in Review blog post.
Internet traffic trends in 2024, worldwide
The West African country of Guinea experienced the most significant Internet traffic growth seen in 2024, reaching as much as 350% above baseline. Traffic growth didn’t begin in earnest until late February, and reached an initial peak in early April. It remained between 100% and 200% above baseline until September, when it experienced several multi-week periods of growth. While the September-November periods of traffic growth also occurred in 2023, they peaked at under 90% above baseline.
The impact of significant Internet outages is also clearly visible when looking at data across the year. Two significant Internet outages in Cuba are clearly visible as large drops in traffic in October and November. A reported “complete disconnection” of the national electricity system on the island occurred on October 18, lasting just over three days. Just a couple of weeks later, on November 6, damage from Hurricane Rafael caused widespread power outages in Cuba, resulting in another large drop in Internet traffic. Traffic has remained lower as Cuba’s electrical infrastructure continues to struggle.
Internet traffic trends in 2024, Cuba
As we frequently discuss in Cloudflare Radar blog and social media posts, government-directed Internet shutdowns occur all too frequently, and the impact of these actions are also clearly visible when looking at long-term traffic data. In Bangladesh, the government ordered the shutdown of mobile Internet connectivity on July 18, in response to student protests. Shortly after mobile networks were shut down, fixed broadband networks were taken offline as well, resulting in a near complete loss of Internet traffic from the country. Connectivity gradually returned over the course of several days, between July 23-28.
Internet traffic trends in 2024, Bangladesh
As we also noted last year, the celebration of major holidays can also have a visible impact on Internet traffic at a country level. For example, in Muslim countries including Indonesia and the United Arab Emirates, the celebration of Eid al-Fitr, the festival marking the end of the fast of Ramadan, is visible as a noticeable drop in traffic around April 9-10.
Internet traffic trends in 2024, Indonesia and United Arab Emirates
Google maintained its position as the most popular Internet service. OpenAI, Binance, WhatsApp, and Facebook led their respective categories.
Over the last several years, the Year In Review has ranked the most popular Internet services. These rankings cover an “overall” perspective, as well as a dozen more specific categories, based on analysis of anonymized query data of traffic to our 1.1.1.1 public DNS resolver from millions of users around the world. For the purposes of these rankings, domains that belong to a single Internet service are grouped together.
Google once again held the top spot overall, supported by its broad portfolio of services, as well as the popularity of the Android mobile operating system (more on that below). Meta properties Facebook, Instagram, and WhatsApp also held spots in the top 10.
Generative AI continued to grow in popularity throughout 2024, and in this category, OpenAI again held the top spot, building on the continued success and popularity of ChatGPT. Within Social Media, the top five remained consistent with 2023’s and 2022’s ranking, including Facebook, TikTok, Instagram, X, and Snapchat.
Global traffic from Starlink grew 3.3x in 2024, in line with last year’s growth rate. After initiating service in Malawi in July 2023, Starlink traffic from that country grew 38x in 2024.
SpaceX’s Starlink continues to be the leading satellite Internet service provider, bringing connectivity to unserved or underserved areas. In addition to opening up new markets in 2024, Starlink also announced relationships to provide in-flight connectivity to multiple airlines, and on cruise ships and trains, as well as enabling subscribers to roam with their subscription using the Starlink Mini.
We analyzed aggregate Cloudflare traffic volumes associated with Starlink’s primary autonomous system (AS14593) to track the growth in usage of the service throughout 2024. Similar to the traffic trends discussed above, the request volume shown on the trend line in the chart represents a seven-day trailing average. Comparisons with 2023 data can be shown by clicking the “Compare” icon at the upper right of the graph. Within comparative views, the lines are scaled to the maximum value shown.
On a worldwide basis, steady, consistent growth was seen across the year, though it accelerates throughout November. This acceleration may have been driven by traffic associated with customer-specific large software updates.
Starlink traffic growth worldwide in 2024
In many locations, there is pent-up demand for “alternative” connectivity providers such as Starlink, and in these countries/regions, we see rapid traffic growth when service becomes available, such as in Zimbabwe. Service availability was announced on September 7, and traffic from the country began to grow rapidly almost immediately thereafter.
Starlink traffic growth in Zimbabwe in 2024
In new markets, traffic growth continues after that initial increase. For example Starlink service became available in Malawi in July 2023, and throughout 2024, Starlink traffic from the country grew 38x. While Malawi’s 38x increase is impressive, other countries also experienced significant growth. In the Eastern European country of Georgia, service became available on November 1, 2023. After a slow ramp, traffic began to take off growing over 100x through 2024. In Paraguay, service availability was announced on December 21, and began to grow at the beginning of January, registering an increase of over 900x across the year.
Starlink traffic growth in Malawi in 2024
Googlebot was responsible for the highest volume of request traffic to Cloudflare in 2024 as it retrieved content from millions of Cloudflare customer sites for search indexing.
Cloudflare Radar shows users Internet traffic trends over a selected period of time, but at a country/region or network level. However, as we did in 2023, we again wanted to look at the traffic Cloudflare saw over the course of the full year from the entire IPv4 Internet. To do so, we can use Hilbert curves, which allow us to visualize a sequence of IPv4 addresses in a two-dimensional pattern that keeps nearby IP addresses close to each other, making them useful for surveying the Internet’s IPv4 address space.
Using a Hilbert curve, we can visualize aggregated IPv4 request traffic to Cloudflare from January 1 through December 1, 2024. Within the visualization, we aggregate IPv4 addresses at a /20 level, meaning that at the highest zoom level, each square represents traffic from 4,096 IPv4 addresses. This aggregation is done to keep the amount of data used for the visualization manageable. (While we would like to create a similar visualization for IPv6 traffic, the enormity of the full IPv6 address space would make associated traffic very hard to see in such a visualization, especially as such a small amount has been allocated for assignment by the Regional Internet Registries.)
Within the visualization, IP addresses are grouped by ownership, and for much of the IP address space shown there, a mouseover at the default zoom level will show the Regional Internet Registry (RIR) that the address block belongs to. However, there are also a number of blocks that were assigned prior to the existence of the RIR system, and for these, they are labeled with the name of the organization that owns them. Progressive zooming ultimately shows the autonomous system and country/region that the IP address block is associated with, as well as its share of traffic relative to the maximum. (If a country/region is selected, only the IP address blocks associated with that location are visible.) Overall traffic shares are indicated by shading based on a color scale, and although a number of large unshaded blocks are visible, this does not necessarily mean that the associated address space is unused, but rather that it may be used in a way that does not generate traffic to Cloudflare.
Hilbert curve showing aggregated 2024 traffic to Cloudflare across the IPv4 Internet
Warmer orange/red shading within the visualization represents areas of higher request volume, and buried within one of those areas is the IP address block that had the maximum request volume to Cloudflare during 2024. As it was in 2023, this address block was 66.249.64.0/20, which belongs to Google, and is one of several used by the Googlebot web crawler to retrieve content for search indexing. This use of that address space is a likely explanation for the high request volume, given the number of web properties on Cloudflare’s network.
Zoomed Hilbert curve view showing the IPv4 address block that generated the highest volume of requests
In addition to Google, owners of other prefixes in the top 20 include Alibaba, Microsoft, Amazon, and Apple. To explore the IPv4 Internet in more detail, we encourage you to go to the Year in Review microsite and explore it by dragging and zooming to move around IPv4 address space.
Among AI bots and crawlers, Bytespider (ByteDance) traffic gradually declined over the course of 2024, while ClaudeBot (Anthropic) was more active during the back half of the year.
AI bots and crawlers have been in the news throughout 2024 as they voraciously consume content to train ever-evolving models. Controversy has followed them, as not all bots and crawlers respect content owner directives to restrict crawling activity. In July, Cloudflare enabled customers to block these bots and crawlers with a single click, and during Birthday Week we introduced AI Audit to give website owners even more visibility into and control over how AI platforms access their content.
Tracking traffic trends for AI bots can help us better understand their activity over time — observing which are the most aggressive and have the highest volume of requests, which perform crawls on a regular basis, etc. The new AI bot & crawler traffic graph on Radar’s Traffic page, launched in September, provides insight into these traffic trends gathered over the selected time period for the top known AI bots.
Looking at traffic trends from two of those bots, we can see some interesting patterns. Bytespider is a crawler operated by ByteDance, the Chinese owner of TikTok, and is reportedly used to download training data for ByteDance’s Large Language Models (LLMs). Bytespider’s crawling activity trended generally downwards over the course of 2024, with end-of-November activity approximately 80-85% lower than that seen at the start of the year. ClaudeBot is Anthropic’s crawler, which downloads training data for its LLMs that power AI products like Claude. Traffic from ClaudeBot appeared to be mostly non-existent through mid-April, except for some small spikes that possibly represent test runs. Traffic became more consistently non-zero starting in late April, but after an early spike, trailed off through the remainder of the year.
Traffic trends for AI crawlers Bytespider and ClaudeBot in 2024
13.0% of TLS 1.3 traffic is using post-quantum encryption.
The term “post-quantum” refers to a new set of cryptographic techniques designed to protect data from adversaries that have the ability to capture and store current data for decryption by sufficiently powerful quantum computers in the future. The Cloudflare Research team has been exploring post-quantum cryptography since 2017.
In October 2022, we enabled post-quantum key agreement on our network by default, but use of it requires that browsers and clients support it as well. In 2024, Google’s Chrome 124 enabled it by default on April 17, and adoption grew rapidly following that release, increasing from just over 2% of requests to around 12% within a month, and ended November at 13%. We expect that adoption will continue to grow into and during 2025 due to support in other Chromium-based browsers, growing default support in Mozilla Firefox, and initial testing in Apple Safari.
Growth trends in post-quantum encrypted TLS 1.3 traffic during 2024
Adoption & Usage insights
Globally, nearly one-third of mobile device traffic was from Apple iOS devices. Android had a >90% share of mobile device traffic in 29 countries/regions; peak iOS mobile device traffic share was over 60% in eight countries/regions.
The two leading mobile device operating systems globally are Apple’s iOS and Google’s Android, and by analyzing information in the user agent reported with each request, we can get insight into the distribution of traffic by client operating system throughout the year. Again, we found that Android is responsible for the majority of mobile device traffic when aggregated globally, due to the wide distribution of price points, form factors, and capabilities.
Global distribution of mobile device traffic by operating system in 2024
In contrast, iOS adoption tops out in the 65% range in Jersey, the Faroe Islands, Guernsey, and Denmark. Adoption rates of 50% or more were seen in a total of 26 countries/regions, including Norway, Sweden, Australia, Japan, the United States, and Canada. These locations likely have a greater ability to afford higher priced devices, owing to their comparatively higher gross national income per capita.
Countries/regions with the largest share of iOS traffic in 2024
Globally, nearly half of web requests used HTTP/2, with 20.5% using HTTP/3.
HTTP (HyperText Transfer Protocol) is the core protocol that the web relies upon. HTTP/1.0 was first standardized in 1996, HTTP/1.1 in 1999, and HTTP/2 in 2015. The most recent version, HTTP/3, was completed in 2022, and runs on top of a new transport protocol known as QUIC. By running on top of QUIC, HTTP/3 can deliver improved performance by mitigating the effects of packet loss and network changes, as well as establishing connections more quickly. HTTP/3 also provides encryption by default, which mitigates the risk of attacks.
Current versions of desktop and mobile Google Chrome (and Chromium-based variants), Mozilla Firefox, and Apple Safari all support HTTP/3 by default. Cloudflare makes HTTP/3 available for free to all of our customers, although not every customer chooses to enable it.
Analysis of the HTTP version negotiated for each request provides insight into the distribution of traffic by the various versions of the protocol aggregated across the year. (“HTTP/1.x” aggregates requests made over HTTP/1.0 and HTTP/1.1.) At a global level, 20.5% of requests in 2024 were made using HTTP/3. Another 29.9% of requests were made over the older HTTP/1.x versions, while HTTP/2 remained dominant, accounting for the remaining 49.6%.
Global distribution of traffic by HTTP version in 2024
Looking at version distribution geographically, we found eight countries/regions sending more than a third of their requests over HTTP/3, with Reunion, Sri Lanka, Mongolia, Greece, and North Macedonia comprising the top five as shown below. Eight other countries/regions, including Iran, Ireland, Hong Kong, and China, sent more than half of their requests over HTTP/1.x throughout 2024. More than half of requests were made over HTTP/2 in a total of 147 countries/regions.
Countries/regions with the largest shares of HTTP/3 traffic in 2024
React, PHP, and jQuery were among the most popular technologies used to build websites, while Hubspot, Google, and WordPress were among the most popular vendors of supporting services and platforms.
Modern websites and applications are extremely complex, built on and integrating on a mix of frameworks, platforms, services, and tools. In order to deliver a seamless user experience, developers must ensure that all of these components happily coexist with each other. Using Cloudflare Radar’s URL Scanner, we again scanned websites associated with the top 5000 domains to identify the most popular technologies and services used across a dozen different categories.
In looking at core technologies used to build websites, React had a commanding lead over Vue.js and other JavaScript frameworks, PHP was the most popular programming technology, and jQuery’s share was 10x other popular JavaScript libraries.
Third-party services and platforms are also used by websites and applications to support things like analytics, content management, and marketing automation. Google Analytics remained the most widely used analytics provider, WordPress had a greater than 50% share among content management systems, and for marketing automation providers, category leader HubSpot had nearly twice the usage share of Marketo and MailChimp.
Top website technologies, JavaScript frameworks category in 2024
Go surpassed NodeJS as the most popular language used for making automated API requests.
Many dynamic websites and applications are built on automated API calls, and we can use our unique visibility into Web traffic to identify the top languages these API clients are written in. Applying heuristics to API-related requests determined to not be coming from a person using a browser or native mobile application helps us to identify the language used to build the API client.
Our analysis found that almost 12% of automated API requests are made by Go-based clients, with NodeJS, Python, Java, and .NET holding smaller shares. Compared to 2023, Go’s share increased by approximately 40%, allowing it to capture the top spot, while NodeJS’s share fell by just over 30%. Python and Java also saw their shares increase, while .NET’s fell.
Most popular API client languages in 2024
Google is the most popular search engine globally, across all platforms. On mobile devices/OS, Baidu is a distant second. Bing is a distant second across desktop and Windows devices, with DuckDuckGo second most popular on macOS.
Protecting and accelerating websites and applications for millions of customers, Cloudflare is in a unique position to measure search engine market share data. Our methodology uses HTTP’s referer header to identify the search engine sending traffic to customer sites and applications. The market share data is presented as an overall aggregate, as well as broken out by device type and operating system. (Device type and operating system data is derived from the User-Agent and Client Hints headers accompanying a content request.)
Aggregated at a global level, Google referred the most traffic to Cloudflare customers, with a greater than 88% share across 2024. Yandex, Baidu, Bing, and DuckDuckGo round out the top five, all with single digit percentage shares.
Overall worldwide search engine market share in 2024
However, when drilling down by location or platform, differences are apparent in the top search engines and their shares. For example, in South Korea, Google is responsible for only two-thirds of referrals, while local platform Naver drives 29.2%, with local portal Daum also in the top five at 1.3%.
Overall search engine market share in South Korea in 2024
Google’s dominance is also blunted a bit on Windows devices, where it drives only 80% of referrals globally. Unsurprisingly, Bing holds the second spot for Windows users, with a 10.4% share. Yandex, Yahoo, and DuckDuckGo round out the top 5, all with shares below 5%.
Overall worldwide search engine market share for Windows devices in 2024
For additional details, including search engines aggregated under “Other”, please refer to the quarterly Search Engine Referral Reports on Cloudflare Radar.
Google Chrome is the most popular browser overall. While also true on MacOS devices, Safari usage is well ahead of Chrome on iOS devices. On Windows, Edge is the second most popular browser.
Similar to our ability to measure search engine market share, Cloudflare is also in a unique position to measure browser market share. Our methodology uses information from the User-Agent and Client Hints headers to identify the browser making content requests, along with the associated operating system. Browser market share data is presented as an overall aggregate, as well as broken out by device type and operating system. Note that the shares of browsers available on both desktop and mobile devices, such as Chrome or Safari, are presented in aggregate.
Globally, we found that 65.8% of requests came from Google’s Chrome browser across 2024, and that just 15.5% came from Apple’s Safari browser. Microsoft Edge, Mozilla Firefox, and the Samsung Internet browser rounded out the top five, all with shares below 10%.
Overall worldwide web browser market share in 2024
Similar to the search engine statistics discussed above, differences are clearly visible when drilling down by location or platform. In some countries where iOS holds a larger market share than Android, Chrome remains the leading browser, but by a much lower margin. For example, in Sweden, Chrome’s share fell to 56.2%, while Safari’s increased to 22.5%. In Norway, Chrome fell to just 50%, while Safari grew to 25.6%.
Overall web browser market share in Norway in 2024
As the default browser on devices running iOS, Apple Safari was the most popular browser for iOS devices, commanding an 81.7% market share across the year, with Chrome at just 16.1%. And despite being the preinstalled default browser on Windows devices, Edge held just a 17.3% share, in comparison to Chrome’s 68.5%
Overall worldwide web browser market share for iOS devices in 2024
For additional details, including browsers aggregated under “Other”, please refer to the quarterly Browser Market Share Reports on Cloudflare Radar.
Connectivity
225 major Internet outages were observed around the world in 2024, with many due to government-directed regional and national shutdowns of Internet connectivity.
Throughout 2024, as we have over the last several years, we have written frequently about observed Internet outages, whether due to cable cuts, unspecified technical issues, government-directed shutdowns, or a number of other reasons covered in our quarterly summary posts (Q1, Q2, Q3). The impacts of these outages can be significant, including significant economic losses and severely limited communications. The Cloudflare Radar Outage Center tracks these Internet outages, and uses Cloudflare traffic data for insights into their scope and duration.
Some of the outages seen through the year were short-lived, lasting just a few hours, while others stretched on for days or weeks. In the latter category, an Internet outage in Haiti dragged on for eight days in September because repair crews were barred from accessing a damaged submarine cable due to a business dispute, while shutdowns of mobile and fixed Internet providers in Bangladesh lasted for approximately 10 days in July. In the former category, Iraq frequently experienced multi-hour nationwide Internet shutdowns intended to prevent cheating on academic exams — these contribute to the clustering visible in the timeline during June, July, August, and September.
Within the timeline on the Year in Review microsite, hovering over a dot will display metadata about that outage, and clicking on it will open a page with additional information. Below the map and timeline, we have added a bar graph illustrating the recorded reasons associated with the observed outages. In 2024, over half were due to government-directed shutdowns. If a country/region is selected, only outages and reasons for that country/region will be displayed.
Over 200 Internet outages were observed around the world during 2024
Aggregated across 2024, 28.5% of IPv6-capable requests were made over IPv6. India and Malaysia were the strongest countries, at 68.9% and 59.6% IPv6 adoption respectively.
The IPv4 protocol still used by many Internet-connected devices was developed in the 1970s, and was never meant to handle the vast and growing scale of the modern Internet. An initial specification for its successor, IPv6, was published in December 1995, evolving to a draft standard three years later, offering an expanded address space intended to better support the expected growth in the number of Internet-connected devices. At this point, available IPv4 space has long since been exhausted, and connectivity providers use solutions like Network Address Translation to stretch limited IPv4 resources. Hungry for IPv4 address space as their businesses and infrastructure grow, cloud and hosting providers are acquiring blocks of IPv4 address space for as much as \$30 – \$50 per address.
Cloudflare has been a vocal and active advocate for IPv6 since 2011, when we announced our Automatic IPv6 Gateway, which enabled free IPv6 support for all of our customers. In 2014, we enabled IPv6 support by default for all of our customers, but not all customers choose to keep it enabled for a variety of reasons. Note that server-side support is only half of the equation for driving IPv6 adoption, as end user connections need to support it as well. (In reality, it is a bit more complex than that, but server and client side support across applications, operating systems, and network environments are the two primary requirements. From a network perspective, implementing IPv6 also brings a number of other benefits.) By analyzing the IP version used for each request made to Cloudflare, aggregated throughout the year, we can get insight into the distribution of traffic by the various versions of the protocol.
At a global level, 28.5% of IPv6-capable (“dual-stack”) requests were made over IPv6, up from 26.4% in 2023. India was again the country with the highest level of IPv6 adoption, at 68.9%, carried in large part by 94% IPv6 adoption at Reliance Jio, one of the country’s largest Internet service providers. India was followed closely by Malaysia, where 59.6% of dual-stacked requests were made over IPv6 during 2024, thanks to strong IPv6 adoption rates across leading Internet providers within the country. IPv6 adoption in India was up from 66% in 2023, and in Malaysia, it was up from 57.3% last year. Saudi Arabia was the only other country with an IPv6 adoption rate above 50% this year, at 51.8%, whereas that list also included Vietnam, Greece, France, Uruguay, and Thailand in 2023. Thirty four countries/regions, including many in Africa, still have IPv6 adoption rates below 1%, while a total of 96 countries/regions have adoption rates below 10%.
Global distribution of traffic by IP version in 2024
Countries/regions with the largest shares of IPv6 traffic in 2024
The top 10 countries ranked by Internet speed all had average download speeds above 200 Mbps. Spain was consistently among the top locations across measured Internet quality metrics.
As more and more of our everyday lives move online, including entertainment, work, education, finance, shopping, and even basic social and personal interaction, the quality of our Internet connections is arguably more important than ever, necessitating higher connection speeds and lower latency. Although Internet providers continue to evolve their service portfolios to offer increased connection speeds and reduced latency in order to support growth in use cases like videoconferencing, live streaming, and online gaming, consumer adoption is often mixed due to cost, availability, or other issues. By aggregating the results of speed.cloudflare.com tests taken during 2024, we can get a geographic perspective on connection quality metrics including average download and upload speeds, and average idle and loaded latencies, as well as the distribution of the measurements.
In 2024, Spain was a leader in download speed (292.6 Mbps) and upload speed (192.6 Mbps) metrics, and placed second globally for loaded latency (78.6 ms). (Loaded latency is the round-trip time when data-heavy applications are being used on the network.) Spain’s leadership in these connection quality metrics is supported by the strong progress that the country has made towards achieving the EU’s “Digital Decade” objectives, including fixed very high capacity network (VHCN) deployment, fiber-to-the-premises (FTTP) coverage, and 5G coverage with the latter two reaching 95.2% and 92.3% respectively. High speed fiber broadband connections are also relatively affordable, with research showing major providers offering 100 Mbps, 300 Mbps, 600 Mbps, and 1 Gbps packages, with the latter priced between €30 and €46 per month. The figures below for Spain show the largest clusters of speed measurements around the 100 Mbps mark, with slight bumps also visible around 300 Mbps, suggesting that the former package has the highest subscription rate, followed by the latter. Further, they show these connections are also relatively low latency, with 87% of idle latency measurements below 50 ms and 65% of loaded latency measurements below 100 ms, providing users with good gaming and videoconferencing/streaming experiences.
Measured download/upload speed distribution in Spain in 2024
Measured idle/loaded latency distribution in Spain in 2024
41.3% of global traffic comes from mobile devices. In nearly 100 countries/regions, the majority of traffic comes from mobile devices.
With approximately 70% of the world’s population using smartphones, and 91% of Americans owning a smartphone, these mobile devices have become an integral part of both our personal and professional lives, providing us with Internet access from nearly any place at any time. In some countries/regions, mobile devices primarily connect to the Internet via Wi-Fi, while other countries/regions are “mobile first”, where 4G/5G services are the primary means of Internet access.
Analysis of information contained with the user agent reported with each request to Cloudflare enables us to categorize it as coming from a mobile, desktop, or other type of device. Aggregating this categorization throughout the year at a global level, we found that 41.3% of traffic came from mobile devices, with 58.7% coming from desktop devices such as laptops and “classic” PCs. These traffic shares were in line with those measured in both 2023 and 2022, suggesting that mobile device usage has achieved a “steady state”. Over 77% of traffic came from mobile devices in Sudan, Cuba, and Syria, making them the countries/regions with the largest mobile device traffic share in 2024. Other countries/regions that had more than 50% of traffic come from mobile devices were concentrated in the Middle East/Africa, the Asia Pacific region, and South/Central America.
Global distribution of traffic by device type in 2024
Countries/regions with the largest shares of mobile device usage in 2024
20.7% of TCP connections are unexpectedly terminated before any useful data can be exchanged.
Cloudflare is in a unique position to help measure the health and behaviors of Internet networks around the world. One way we do this is passively measuring rates of connections to Cloudflare that appear anomalous, meaning that they are unexpectedly terminated before any useful data exchange occurs. The underlying causes of connection anomalies are varied and range from DoS attacks to quirky client behavior to third-party connection tampering (e.g., when a network monitors and selectively disrupts connections to filter content).
Connection anomalies are symptoms — visible signs that “something abnormal” is happening in a network, but the underlying root cause is not always clear from the outset. However, we can gain a better understanding by incorporating previously-reported network behaviors, active measurements and on-the-ground reports, and macro trends across networks. Additional details on such analysis can be found in the blog posts A global assessment of third-party connection tampering andBringing insights into TCP resets and timeouts to Cloudflare Radar.
Insights into TCP connection anomalies were launched on Cloudflare Radar in September, with the plot lines in the associated graph corresponding to the stage of the TCP connection in which the connection anomalously closed (using shorthand, the first three messages we typically receive from the client in a TCP connection are “SYN” and “ACK” packets to establish a connection, and then a “PSH” packet indicating the requested resource). In aggregate globally, over 20% of connections to Cloudflare were terminated unexpectedly, with the largest share (nearly half) being closed “Post SYN” — that is, after our server has received a client’s SYN packet, but before we have received a subsequent acknowledgement (ACK) from the client or any useful data that would follow the acknowledgement. These terminations can often be attributed to DoS attacks or Internet scanning. Post-ACK (3.1% globally) and Post-PSH (1.4% globally) anomalies are more often associated with connection tampering, especially when they occur at high rates in specific networks.
Trends in TCP connection anomalies by stage in 2024
Security
6.5% of global traffic was mitigated by Cloudflare’s systems as being potentially malicious or for customer-defined reasons.
To protect customers from threats posed by malicious bots used to attack websites and applications, Cloudflare mitigates this attack traffic using DDoS mitigation techniques or Web Application Firewall (WAF) Managed Rules. For a variety of other reasons, customers may also want Cloudflare to mitigate traffic using techniques like rate-limiting requests, or blocking all traffic from a given location, even if it isn’t malicious. Analyzing traffic to Cloudflare’s network throughout 2024, we looked at the overall share that was mitigated for any reason, as well as the share that was blocked as a DDoS attack or by WAF Managed Rules.
In 2024, 6.5% of global traffic was mitigated, up almost one percentage point from 2023. Just 3.2% was mitigated as a DDoS attack, or by WAF Managed Rules, a rate slightly higher than in 2023. More than 10% of the traffic originating from 44 countries/regions had mitigations generally applied, while DDoS/WAF mitigations were applied to more than 10% of the traffic originating from just seven countries/regions.
At a country/region level, Albania had one of the highest mitigated traffic shares throughout the year, at 42.9%, while Libya had one of the highest shares of traffic that was mitigated as a DDoS attack or by WAF Managed Rules, at 19.2%. In 2023’s Year in Review blog post, we highlighted the United States and Korea. This year, the share of mitigated traffic grew to 5.0% in the United States (up from 3.65% in 2023), while in South Korea, it dropped slightly to 8.1%, down from 8.36%.
Trends in mitigated traffic worldwide in 2024
The United States was responsible for over a third of global bot traffic. Amazon Web Services was responsible for 12.7% of global bot traffic, and 7.8% came from Google.
Bot traffic describes any non-human Internet traffic, and by monitoring traffic suspected to be from bots site and application owners can spot and, if necessary, block potentially malicious activity. However, not all bots are malicious — bots can also be helpful, and Cloudflare maintains a list of verified bots that includes those used for things like search engine indexing, performance testing, and availability monitoring. Regardless of intent, we analyzed where bot traffic was originating from in 2024, using the IP address of a request to identify the network (autonomous system) and country/region associated with the bot making the request. Cloud platforms remained among the leading sources of bot traffic due to a number of factors. These include the ease of using automated tools to quickly provision compute resources, the relatively low cost of using these compute resources in an ephemeral manner, the broadly distributed geographic footprint of cloud platforms, and the platforms’ high-bandwidth Internet connectivity.
Globally, we found that 68.5% of observed bot traffic came from the top 10 countries in 2024, with the United States responsible for half of that total, over 5x the share of second place Germany. (In comparison to 2023, the US share was up slightly, while Germany’s was down slightly.) Among cloud platforms that originate bot traffic, Amazon Web Services was responsible for 12.7% of global bot traffic, and 7.8% came from Google. Microsoft, Hetzner, Digital Ocean, and OVH all also contributed more than a percent each.
Global bot traffic distribution by source country in 2024
Global bot traffic distribution by source network in 2024
Globally, Gambling/Games was the most attacked industry, slightly ahead of 2023’s most targeted industry, Finance.
The industries targeted by attacks often shift over time, depending on the intent of the attackers. They may be trying to cause financial harm by attacking ecommerce sites during a busy shopping period, gain an advantage against opponents by attacking an online game, or make a political statement by attacking government-related sites. To identify industry-targeted attack activity during 2024, we analyzed mitigated traffic for customers that had an associated industry and vertical within their customer record. Mitigated traffic was aggregated weekly by source country/region across 19 target industries.
Companies in the Gambling/Games industry were, in aggregate, the most attacked during 2024, with 6.6% of global mitigated traffic targeting the industry. The industry was slightly ahead of Finance, which led 2023’s aggregate list. (Both industries are shown at 6.6% in the Summary view due to rounding.) Gambling/Games sites saw the largest shares of mitigated traffic in January and the first week of February, possibly related to National Football League playoffs in the United States, heading into the Super Bowl.
Attacks targeting Finance organizations were most active in May, reaching a peak of 15.3% of mitigated traffic the week of May 13. This is in line with the figure in our DDoS threat report for Q2 2024 that shows that Financial Services was the most attacked industry by request volume during the quarter in South America and the Middle East region.
As we have seen in the past, peak attack activity varied by industry on a weekly basis. The highest peaks for the year were seen in attacks targeting People & Society organizations (19.6% of mitigated traffic, week of January 1), the Autos & Vehicles industry (29.7% of mitigated traffic, week of January 15), and the Real Estate industry (27.5% of mitigated traffic, week of August 26).
Global mitigated traffic share by industry in 2024, summary view
Log4j remains a persistent threat and was actively targeted throughout 2024.
In December 2021, we published a series of blog posts about the Log4j vulnerability, highlighting the threat that it posed, our observations of attempted exploitation, and the steps we took to protect customers. Two years on, in our 2023 Year in Review, we noted that even as an older vulnerability, Log4j remained a top target for attacks during 2023, with related attack activity significantly higher than other commonly exploited vulnerabilities.
In 2024, three years after the initial Log4j disclosure, we found that Log4j remains an active threat. This year, we compared normalized daily attack activity for Log4j with attack activity for Atlassian Confluence Code Injection, a vulnerability we examined in the 2023 Year in Review, as well as aggregated daily attack activity for multiple CVEs related to Authentication Bypass and Remote Code Execution vulnerabilities published in 2024.
Log4j attack activity appeared to trend generally upwards across the year, with several significant spikes visible during the first half of the year, and then again in October and November. In terms of the difference in activity, Log4j ranges from approximately 4x to over 20x the activity seen for Atlassian Confluence Code Injection, and as much as 100x the aggregated activity seen for Authentication Bypass or Remote Code Injection vulnerabilities.
Global attack activity trends for commonly exploited vulnerabilities in 2024
Routing security, measured as the share of RPKI valid routes and the share of covered IP address space, continued to improve globally throughout 2024.
As the routing protocol that underpins the Internet, Border Gateway Protocol (BGP) communicates routes between networks, enabling traffic to flow between source and destination. BGP, however, relies on trust between networks, and incorrect information shared between peers, whether or not it was shared intentionally, can send traffic to the wrong place, potentially with malicious results. Resource Public Key Infrastructure (RPKI) is a cryptographic method of signing records that associate a BGP route announcement with the correct originating autonomous system (AS) number, providing a way of ensuring that the information being shared originally came from a network that is allowed to do so. (It is important to note that this is only half of the challenge of implementing routing security, because network providers also need to validate these signatures and filter out invalid announcements to prevent sharing them further.)
Cloudflare has long been an advocate for routing security, including being a founding participant in the MANRS CDN and Cloud Programme and providing a public tool that enables users to test whether their Internet provider has implemented BGP safely. Building on insights available in the Routing page on Cloudflare Radar, we analyzed data from RIPE NCC’s RPKI daily archive to determine the share of RPKI valid routes (as opposed to those route announcements that are invalid or whose status is unknown) and how that share has changed over the course of 2024, as well as determining the share of IP address space covered by valid routes. The latter metric is of interest because a route announcement covering a significant amount of IP address space (millions of IPv4 addresses, for example) has a greater potential impact than an announcement covering a small block of IP address space (hundreds of IPv4 addresses, for example).
At a global level during 2024, we saw a 6.4 percentage point increase (from 43.4% to 49.8%) in valid IPv4 routes, and a 3.2 percentage point increase (from 53.7% to 56.9%) in valid IPv6 routes. Given the trajectory, it is likely that over half of IPv4 routes will be RPKI valid by the end of calendar year 2024. Looking at the global share of IP address space covered by valid routes, we saw a 4.7 percentage point increase (from 38.9% to 43.6%) for IPv4, and a 3.3 percentage point increase (from 57.6% to 60.9%) for IPv6.
Shares of global RPKI valid routing entries by IP version in 2024
Shares of globally announced IP address space covered by RPKI valid routes in 2024
Spain started 2024 with less than half of its routes (both IPv4 and IPv6) RPKI valid. However, the share of valid routes grew significantly on February 15, when AS12479 (Orange Espagne) signed records associated with 98% of their IP address prefixes that were previously in an “unknown” (or NotFound) state of RPKI validity, thus converting these prefixes from unknown to valid. That drove an immediate increase for IPv4 to 76%, reaching 81% validity by December 1, and an immediate increase for IPv6 to 91%, reaching 92.9% validity by December 1. A notable change in covered IP address space was observed in Cameroon, where covered IPv4 space more than doubled at the end of January, growing from 32% to 82%. This was due to AS36912 (Orange Cameroun) signing records associated with all of their IPv4 address prefixes, changing the associated IP address space to RPKI valid.
IPv4 and IPv6 shares of RPKI valid routes for Spain in 2024
Share of IPv4 address space covered by RPKI valid routes for Cameroon in 2024
Email Security
An average of 4.3% of emails were determined to be malicious in 2024.
Despite the growing enterprise use of collaboration/messaging apps, email remains an important business application and is a very attractive entry point into enterprise networks for attackers. Attackers will send targeted malicious emails that attempt to impersonate an otherwise legitimate sender (such as a corporate executive), that try to get the user to click on a deceptive link, or that contain a dangerous attachment, among other types of threats. Cloudflare Email Security protects customers from email-based attacks, including those carried out through targeted malicious email messages. During 2024, an average of 4.3% of emails analyzed by Cloudflare were found to be malicious. Aggregated at a weekly level, spikes above 14% were seen in late March, early April, and mid-May. We believe that these spikes were related to targeted “backscatter” attacks, where the attacker flooded a target with undeliverable messages, which then bounced the messages to the victim, whose email had been set as the reply-to: address.
Global malicious email share trends in 2024
Deceptive links and identity deception were the two most common types of threats found in malicious email messages.
Attackers use a variety of techniques, which we refer to as threat categories, when they use malicious email messages as an attack vector. These categories are defined and explored in detail in our phishing threats report. In our analysis of malicious emails, we have found that such messages may contain multiple types of threats. In reviewing a weekly aggregation of threat activity trends for these categories, we found that, averaged across 2024, 42.9% of malicious email messages contained deceptive links, with the share reaching 70% at times throughout the year. Activity for this thread category was spiky, with low points seen in the March to May timeframe, and a general downward trend visible from July through November.
Identity deception was a similarly active threat category, with such threats also found in up to 70% of analyzed emails several weeks throughout the year. Averaged across 2024, 35.1% of emails contained attempted identity deception. The activity pattern for this threat category appears to be somewhat similar to deceptive links, with a number of the peaks and valleys occurring during the same weeks. At times, identity deception was a more prevalent threat in analyzed emails than deceptive links, as seen in the graph below.
Among other threat categories, extortion saw the most significant change throughout the year. After being found in 86% of malicious emails during the first week of January, its share gradually trended lower throughout the year, finishing November under 10%.
Global malicious email threat category trends for Deceptive Links and Identity Deception in 2024
Over 99% of the email messages processed by Cloudflare Email Security from the .bar, .rest, and .uno top level domains (TLDs) were found to be either spam or malicious in nature.
In March 2024, we launched a set of email security insights on Cloudflare Radar, including visibility into so-called “dangerous domains” — those top level domains (TLDs) that were found to be the sources of the most spam or malicious email among messages analyzed by Cloudflare Email Security. The analysis is based on the sending domain’s TLD, found in the From: header of an email message. For example, if a message came from [email protected], then example.com is the sending domain, and .com is the associated TLD.
In aggregate across 2024, we found that the .bar, .rest, and .uno TLDs were the “most dangerous”, each with over 99% of analyzed email messages characterized as either spam or malicious. (These TLDs are all at least a decade old, and each sees at least some usage, with between 20,000 and 60,000 registered domain names.) Sorting by malicious email share, the .ws ccTLD (country code top level domain) belonging to Western Samoa came out on top, with over 90% of analyzed emails categorized as malicious. Sorting by spam email share, .quest is the biggest offender, with over 88% of emails originating from associated domains characterized as spam.
TLDs originating the largest total shares of malicious and spam email in 2024
Conclusion
The Internet is an amazingly complex and dynamic organism, constantly changing, growing, and evolving.
With the Cloudflare Radar 2024 Year In Review, we are providing insights into the change, growth, and evolution that we have measured and observed throughout the year. Trend graphs, maps, tables, and summary statistics provide our unique perspectives on Internet traffic, Internet quality, and Internet security, and how key metrics across these areas vary around the world and over time.
We strongly encourage you to visit the Cloudflare Radar 2024 Year In Review microsite and explore the trends for your country/region, and to consider how they impact your organization so that you are appropriately prepared for 2025. In addition, for insights into the top Internet services across multiple industry categories, we encourage you to read the companion Year in Review blog post, From ChatGPT to Temu: ranking top Internet services in 2024.
As it is every year, it truly is a team effort to produce the data, microsite, and content for our annual Year in Review, and I’d like to acknowledge those team members that contributed to this year’s effort. Thank you to: Jorge Pacheco, Sabina Zejnilovic, Carlos Azevedo, Mingwei Zhang (Data Analysis); André Jesus, Nuno Pereira (Front End Development); João Tomé (Most popular Internet services); Jackie Dutton, Kari Linder, Guille Lasarte (Communications); Eunice Giles (Brand Design); Jason Kincaid (blog editing); and Paula Tavares (Engineering Management), as well as countless other colleagues for their answers, edits, support, and ideas.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.



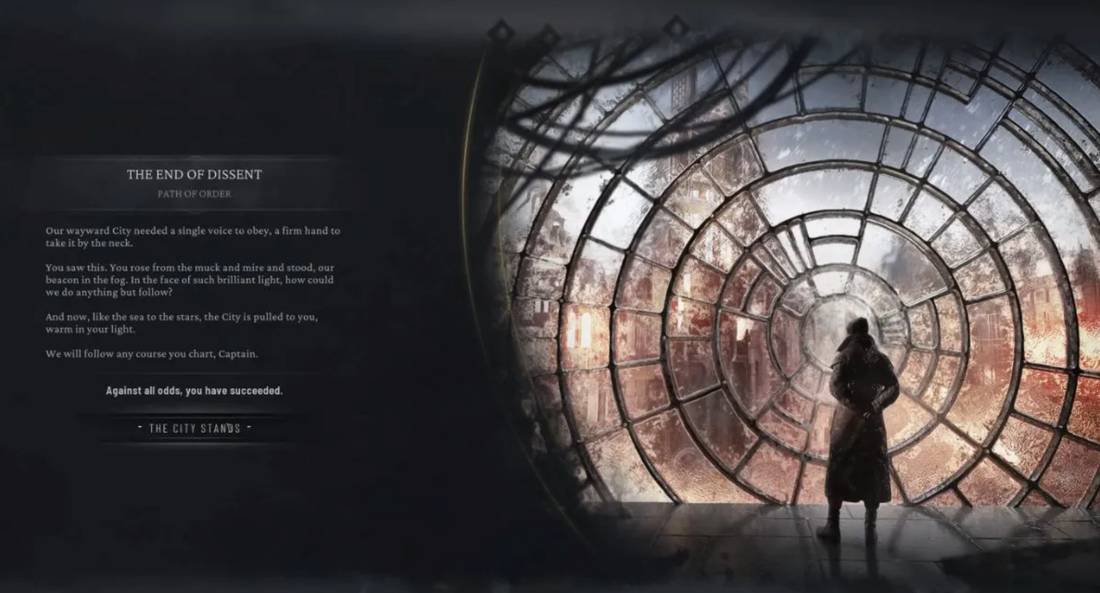
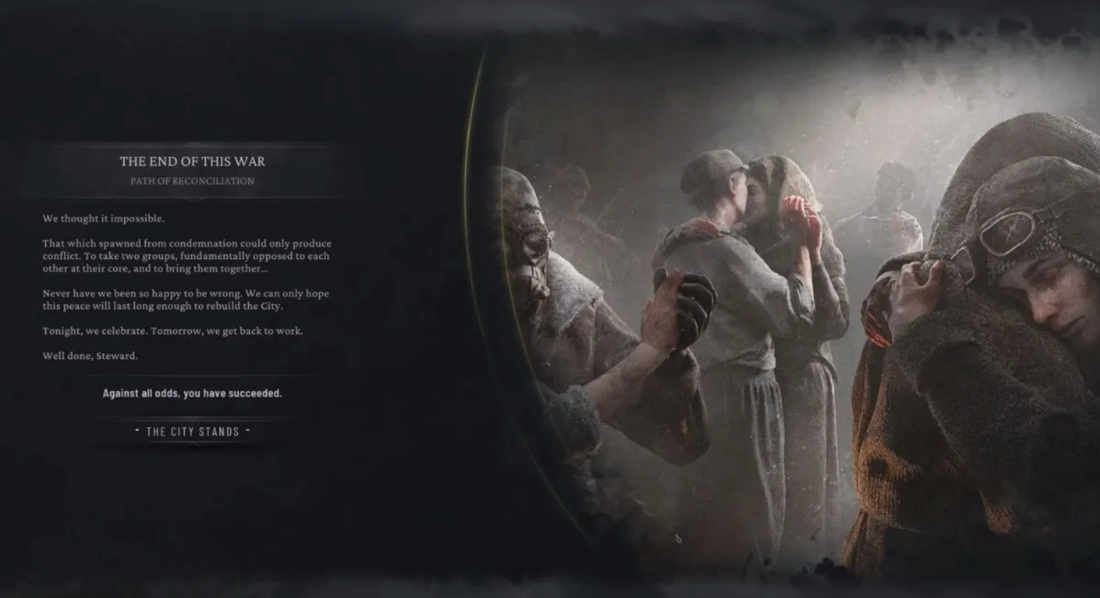
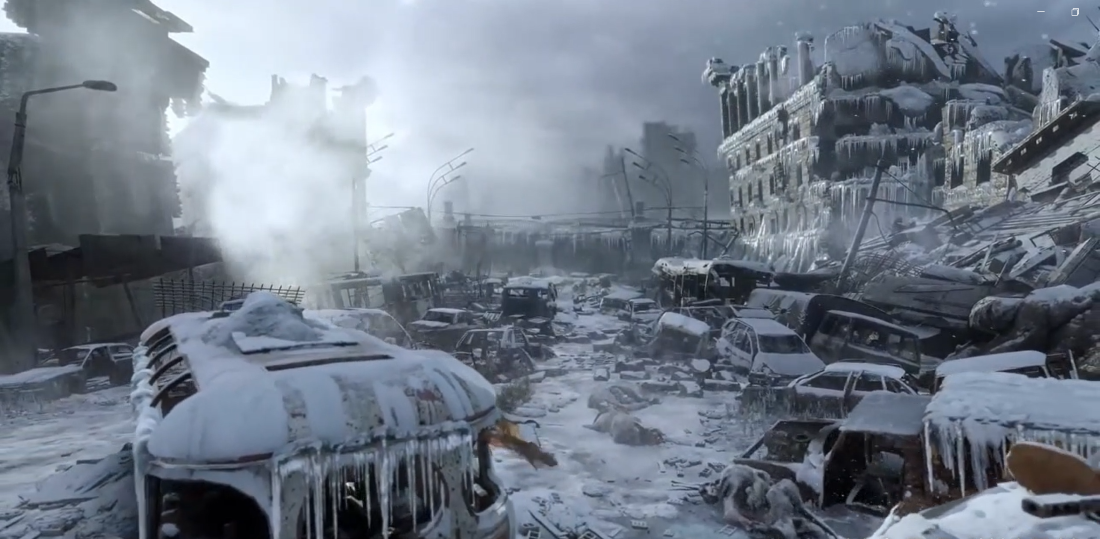
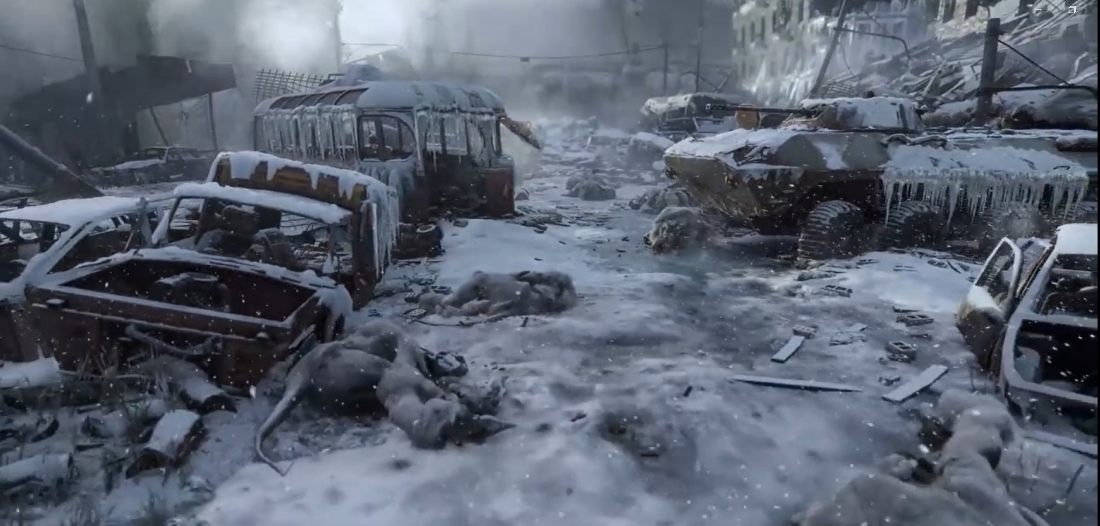
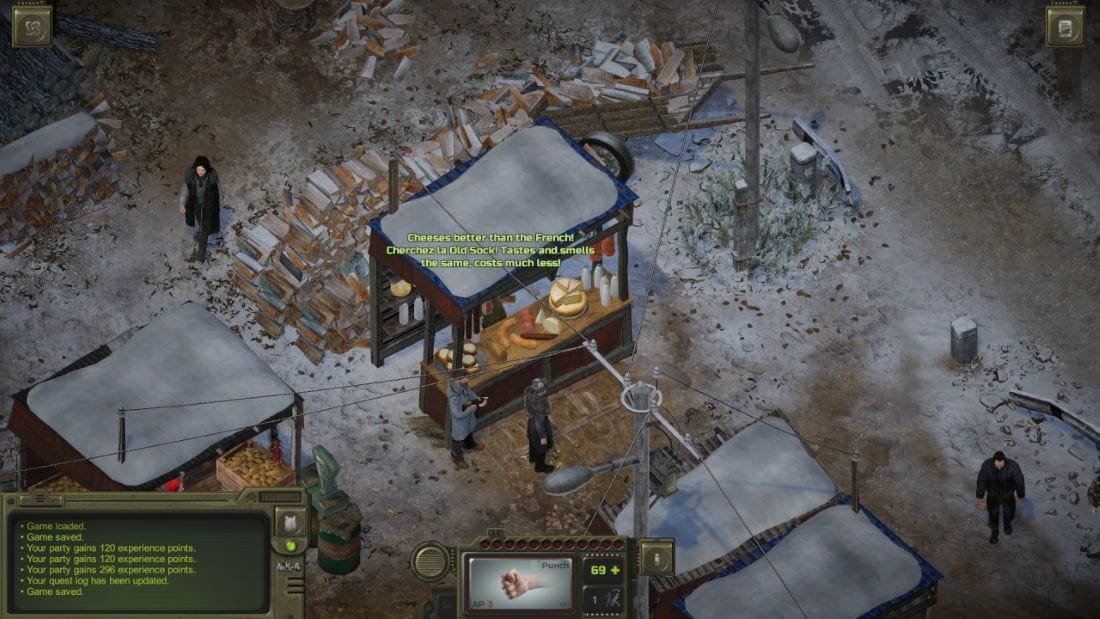
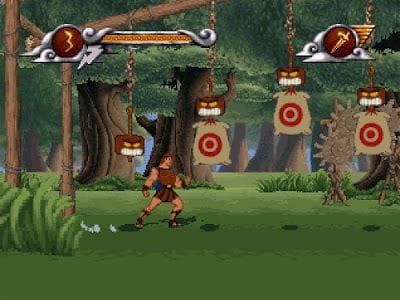
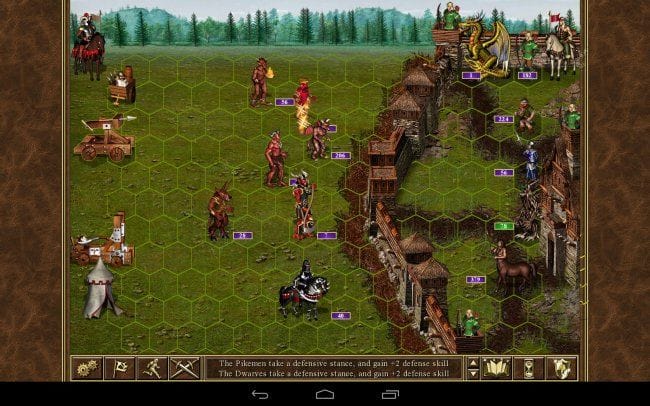




 Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.
 Sotaro Hikita is a Solutions Architect. He supports customers in a wide range of industries, especially the financial industry, to build better solutions. He is particularly passionate about big data technologies and open source software.
 Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.