Managing to-do lists is something of a universal necessity. While some
people handle them mentally or on paper, others resort to a web-based tool or
a mobile
application. For those preferring the command line, the MIT-licensed Taskwarrior offers a flexible solution
with a healthy community and lots of extensions.
Amazon OpenSearch Service recently introduced the OpenSearch Optimized Instance family (OR1), which delivers up to 30% price-performance improvement over existing memory optimized instances in internal benchmarks, and uses Amazon Simple Storage Service (Amazon S3) to provide 11 9s of durability. With this new instance family, OpenSearch Service uses OpenSearch innovation and AWS technologies to reimagine how data is indexed and stored in the cloud.
Today, customers widely use OpenSearch Service for operational analytics because of its ability to ingest high volumes of data while also providing rich and interactive analytics. In order to provide these benefits, OpenSearch is designed as a high-scale distributed system with multiple independent instances indexing data and processing requests. As your operational analytics data velocity and volume of data grows, bottlenecks may emerge. To sustainably support high indexing volume and provide durability, we built the OR1 instance family.
In this post, we discuss how the reimagined data flow works with OR1 instances and how it can provide high indexing throughput and durability using a new physical replication protocol. We also dive deep into some of the challenges we solved to maintain correctness and data integrity.
Designing for high throughput with 11 9s of durability
OpenSearch Service manages tens of thousands of OpenSearch clusters. We’ve gained insights into typical cluster configurations that customers use to meet high throughput and durability goals. To achieve higher throughput, customers often choose to drop replica copies to save on the replication latency; however, this configuration results in sacrificing availability and durability. Other customers require high durability and as a result need to maintain multiple replica copies, resulting in higher operating costs for them.
The OpenSearch Optimized Instance family provides additional durability while also keeping costs lower by storing a copy of the data on Amazon S3. With OR1 instances, you can configure multiple replica copies for high read availability while maintaining indexing throughput. The following diagram illustrates an indexing flow involving a metadata update in OR1
During indexing operations, individual documents are indexed into Lucene and also appended to a write-ahead log also known as a translog. Before sending back an acknowledgement to the client, all translog operations are persisted to the remote data store backed by Amazon S3. If any replica copies are configured, the primary copy performs checks to detect the possibility of multiple writers (control flow) on all replica copies for correctness reasons. The following diagram illustrates the segment generation and replication flow in OR1 instances
Periodically, as new segment files are created, the OR1 copy those segments to Amazon S3. When the transfer is complete, the primary publishes new checkpoints to all replica copies, notifying them of a new segment being available for download. The replica copies subsequently download newer segments and make them searchable. This model decouples the data flow that happens using Amazon S3 and the control flow (checkpoint publication and term validation) that happens over inter-node transport communication.
The following diagram illustrates the recovery flow in OR1 instances
OR1 instances persist not only the data, but the cluster metadata like index mappings, templates, and settings in Amazon S3. This makes sure that in the event of a cluster-manager quorum loss, which is a common failure mode in non-dedicated cluster-manager setups, OpenSearch can reliably recover the last acknowledged metadata.
In the event of an infrastructure failure, an OpenSearch domain can end up losing one or more nodes. In such an event, the new instance family guarantees recovery of both the cluster metadata and the index data up to the latest acknowledged operation. As new replacement nodes join the cluster, the internal cluster recovery mechanism bootstraps the new set of nodes and then recovers the latest cluster metadata from the remote cluster metadata store. After the cluster metadata is recovered, the recovery mechanism starts to hydrate the missing segment data and translog from Amazon S3. Then all uncommitted translog operations, up to the last acknowledged operation, are replayed to reinstate the lost copy.
The new design doesn’t modify the way searches work. Queries are processed normally by either the primary or replica shard for each shard in the index. You may see longer delays (in the 10-second range) before all copies are consistent to a particular point in time because the data replication is using Amazon S3.
A key advantage of this architecture is that it serves as a foundational building block for future innovations, like separation of readers and writers, and helps segregate compute and storage layers.
How redefining the replication strategy boosts the indexing throughput
OpenSearch supports two replication strategies: logical (document) and physical (segment) replication. In the case of logical replication, the data is indexed on all the copies independently, leading to redundant computation on the cluster. The OR1 instances use the new physical replication model, where data is indexed only on the primary copy and additional copies are created by copying data from the primary. With a high number of replica copies, the node hosting the primary copy requires significant network bandwidth, replicating the segment to all the copies. The new OR1 instances solve this problem by durably persisting the segment to Amazon S3, which is configured as a remote storage option. They also help with scaling replicas without bottlenecking on primary.
After the segments are uploaded to Amazon S3, the primary sends out a checkpoint request, notifying all replicas to download the new segments. The replica copies then need to download the incremental segments. Because this process frees up compute resources on replicas, which is otherwise required to redundantly index data and network overhead incurred on primaries to replicate data, the cluster is able to churn more throughput. In the event the replicas aren’t able to process the newly created segments, due to overload or slow network paths, the replicas beyond a point are marked as failed to prevent them from returning stale results.
Why high durability is a good idea, but hard to do well
Although all committed segments are durably persisted to Amazon S3 whenever they get created, one of key challenges in achieving high durability is synchronously writing all uncommitted operations to a write-ahead log on Amazon S3, before acknowledging back the request to the client, without sacrificing throughput. The new semantics introduce additional network latency for individual requests, but the way we’ve made sure there is no impact to throughput is by batching and draining requests on a single thread for up to a specified interval, while making sure other threads continue to index requests. As a result, you can drive higher throughput with more concurrent client connections by optimally batching your bulk payloads.
Other challenges in designing a highly durable system include enforcing data integrity and correctness at all times. Although some events like network partitions are rare, they can break the correctness of the system and therefore the system needs to be prepared to deal with these failure modes. Therefore, while switching to the new segment replication protocol, we also introduced a few other protocol changes, like detecting multiple writers on each replica. The protocol makes sure that an isolated writer can’t acknowledge a write request, while another newly promoted primary, based on the cluster-manager quorum, is concurrently accepting newer writes.
The new instance family automatically detects the loss of a primary shard while recovering data, and performs extensive checks on network reachability before the data can be re-hydrated from Amazon S3 and the cluster is brought back to a healthy state.
For data integrity, all files are extensively checksummed to make sure we are able to detect and prevent network or file system corruption that may result in data being unreadable. Furthermore, all files including metadata are designed to be immutable, providing additional safety against corruptions and versioned to prevent accidental mutating changes.
Reimagining how data flows
The OR1 instances hydrate copies directly from Amazon S3 in order to perform recovery of lost shards during an infrastructure failure. By using Amazon S3, we are able to free up the primary node’s network bandwidth, disk throughput, and compute, and therefore provide a more seamless in-place scaling and blue/green deployment experience by orchestrating the entire process with minimal primary node coordination.
OpenSearch Service provides automatic data backups called snapshots at hourly intervals, which means in case of accidental modifications to data, you have the option to go back to a previous point in time state. However, with the new OpenSearch instance family, we’ve discussed that the data is already durably persisted on Amazon S3. So how do snapshots work when we already have the data present on Amazon S3?
With the new instance family, snapshots serve as checkpoints, referencing the already present segment data as it exists at a point in time. This makes snapshots more lightweight and faster because they don’t need to re-upload any additional data. Instead, they upload metadata files that capture the view of the segments at that point in time, which we call shallow snapshots. The benefit of shallow snapshots extends to all operations, namely creation, deletion, and cloning of snapshots. You still have the option to snapshot an independent copy with manual snapshots for other administrative operations.
Summary
OpenSearch is an open source, community-driven software. Most of the foundational changes including the replication model, remote-backed storage, and remote cluster metadata have been contributed to open source; in fact, we follow an open source first development model.
Efforts to improve throughput and reliability is a never-ending cycle as we continue to learn and improve. The new OpenSearch optimized instances serve as a foundational building block, paving the way for future innovations. We are excited to continue our efforts in improving reliability and performance and to see what new and existing solutions builders can create using OpenSearch Service. We hope this leads to a deeper understanding of the new OpenSearch instance family, how this offering achieves high durability and better throughput, and how it can help you configure clusters based on the needs of your business.
If you’re excited to contribute to OpenSearch, open up a GitHub issue and let us know your thoughts. We would also love to hear about your success stories achieving high throughput and durability on OpenSearch Service. If you have other questions, please leave a comment.
About the Authors
Bukhtawar Khan is a Principal Engineer working on Amazon OpenSearch Service. He is interested in building distributed and autonomous systems. He is a maintainer and an active contributor to OpenSearch.
Gaurav Bafna is a Senior Software Engineer working on OpenSearch at Amazon Web Services. He is fascinated about solving problems in distributed systems. He is a maintainer and an active contributor to OpenSearch.
Sachin Kale is a senior software development engineer at AWS working on OpenSearch.
Rohin Bhargava is a Sr. Product Manager with the Amazon OpenSearch Service team. His passion at AWS is to help customers find the correct mix of AWS services to achieve success for their business goals.
Ranjith Ramachandra is a Senior Engineering Manager working on Amazon OpenSearch Service. He is passionate about highly scalable distributed systems, high performance and resilient systems.
Analytics as a service (AaaS) is a business model that uses the cloud to deliver analytic capabilities on a subscription basis. This model provides organizations with a cost-effective, scalable, and flexible solution for building analytics. The AaaS model accelerates data-driven decision-making through advanced analytics, enabling organizations to swiftly adapt to changing market trends and make informed strategic choices.
The Powered by Amazon Redshift program helps AWS Partners operating an AaaS model quickly build analytics applications using Amazon Redshift and successfully scale their business. For example, you can build visualizations on top of Amazon Redshift and embed them within applications to provide outstanding analytics experiences for end-users. In this post, we explore how AaaS providers scale their processes with Amazon Redshift to deliver insights to their customers.
AaaS delivery models
While serving analytics at scale, AaaS providers and customers can choose where to store the data and where to process the data.
AaaS providers could choose to ingest and process all the customer data into their own account and deliver insights to the customer account. Alternatively, they could choose to directly process data in-place within the customer’s account.
The choice of these delivery models depends on many factors, and each has their own benefits. Because AaaS providers service multiple customers, they could mix these models in a hybrid fashion, meeting each customer’s preference. The following diagram illustrates the two delivery models.
We explore the technical details of each model in the next sections.
Build AaaS on Amazon Redshift
Amazon Redshift has features that allow AaaS providers the flexibility to deploy three unique delivery models:
Managed model – Processing data within the Redshift data warehouse the AaaS provider manages
Bring-your-own-Redshift (BYOR) model – Processing data directly within the customer’s Redshift data warehouse
Hybrid model – Using a mix of both models depending on customer needs
These delivery models give AaaS providers the flexibility to deliver insights to their customers no matter where the data warehouse is located.
Let’s look at how each of these delivery models work in practice.
Managed model
In this model, the AaaS provider ingests customer data in their own account, and engages their own Redshift data warehouse for processing. Then they use one or more methods to deliver the generated insights to their customers. Amazon Redshift enables companies to securely build multi-tenant applications, ensuring data isolation, integrity, and confidentiality. It provides features like row-level security (RLS), column-level security (CLS) for fine-grained access control, role-based access control (RBAC), and assigning permissions at the database and schema level.
The following diagram illustrates the managed delivery model and the various methods AaaS providers can use to deliver insights to their customers.
The workflow includes the following steps:
The AaaS provider pulls data from customer data sources like operational databases, files, and APIs, and ingests them into the Redshift data warehouse hosted in their account.
Data processing jobs enrich the data in Amazon Redshift. This could be an application the AaaS provider has built to process data, or they could use a data processing service like Amazon EMR or AWS Glue to run Spark applications.
Now the AaaS provider has multiple methods to deliver insights to their customers:
Option 1 – The enriched data with insights is shared directly with the customer’s Redshift instance using the Amazon Redshift data sharing feature. End-users consume data using business intelligence (BI) tools and analytics applications.
Option 2 – If AaaS providers are publishing generic insights to AWS Data Exchange to reach millions of AWS customers and monetize those insights, their customers can use AWS Data Exchange for Amazon Redshift. With this feature, customers get instant insights in their Redshift data warehouse without having to write extract, transform, and load (ETL) pipelines to ingest the data. AWS Data Exchange provides their customers a secure and compliant way to subscribe to the data with consolidated billing and subscription management.
Option 3 – The AaaS provider exposes insights on a web application using the Amazon Redshift Data API. Customers access the web application directly from the internet. The gives the AaaS provider the flexibility to expose insights outside an AWS account.
Option 4 – Customers connect to the AaaS provider’s Redshift instance using Amazon QuickSight or other third-party BI tools through a JDBC connection.
In this model, the customer shifts the responsibility of data management and governance to the AaaS providers, with light services to consume insights. This leads to improved decision-making as customers focus on core activities and save time from tedious data management tasks. Because AaaS providers move data from the customer accounts, there could be associated data transfer costs depending on how they move the data. However, because they deliver this service at scale to multiple customers, they can offer cost-efficient services using economies of scale.
BYOR model
In cases where the customer hosts a Redshift data warehouse and wants to run analytics in their own data platform without moving data out, you use the BYOR model.
The following diagram illustrates the BYOR model, where AaaS providers process data to add insights directly in their customer’s data warehouse so the data never leaves the customer account.
The solution includes the following steps:
The customer ingests all the data from various data sources into their Redshift data warehouse.
The data undergoes processing:
The AaaS provider uses a secure channel, AWS PrivateLink for the Redshift Data API, to push data processing logic directly in the customer’s Redshift data warehouse.
They use the same channel to process data at scale with multiple customers. The diagram illustrates a second customer, but this can scale to hundreds or thousands of customers. AaaS providers can tailor data processing logic per customer by isolating scripts for each customer and deploying them according to the customer’s identity, providing a customized and efficient service.
The customer’s end-users consume data from their own account using BI tools and analytics applications.
The customer has control over how to expose insights to their end-users.
This delivery model allows customers to manage their own data, reducing dependency on AaaS providers and cutting data transfer costs. By keeping data in their own environment, customers can reduce the risk of data breach while benefiting from insights for better decision-making.
Hybrid model
Customers have diverse needs influenced by factors like data security, compliance, and technical expertise. To cover a broader range of customers, AaaS providers can choose a hybrid approach that delivers both the managed model and the BYOR model depending on the customer, offering flexibility and the ability to serve multiple customers.
The following diagram illustrates the AaaS provider delivering insights through the BYOR model for Customer 1 and 4, the managed model for Customer 2 and 3, and so on.
Conclusion
In this post, we talked about the rising demand of analytics as a service and how providers can use the capabilities of Amazon Redshift to deliver insights to their customers. We examined two primary delivery models: the managed model, where AaaS providers process data on their own accounts, and the BYOR model, where AaaS providers process and enrich data directly in their customer’s account. Each method offers unique benefits, such as cost-efficiency, enhanced control, and personalized insights. The flexibility of the AWS Cloud facilitates a hybrid model, accommodating diverse customer needs and allowing AaaS providers to scale. We also introduced the Powered by Amazon Redshift program, which supports AaaS businesses in building effective analytics applications, fostering improved user engagement and business growth.
We take this opportunity to invite our ISV partners to reach out to us and learn more about the Powered by Amazon Redshift program.
About the Authors
Sandipan Bhaumik is a Senior Analytics Specialist Solutions Architect based in London, UK. He helps customers modernize their traditional data platforms using the modern data architecture in the cloud to perform analytics at scale.
Sain Das is a Senior Product Manager on the Amazon Redshift team and leads Amazon Redshift GTM for partner programs, including the Powered by Amazon Redshift and Redshift Ready programs.
In the ever-evolving landscape of cyber threats, a subtle yet potent form of phishing has emerged — quishing, short for QR phishing. It has been 30 years since the invention of QR codes, yet quishing still poses a significant risk, especially after the era of COVID, when QR codes became the norm to check statuses, register for events, and even order food.
Since 2020, Cloudflare’s cloud email security solution (previously known as Area 1) has been at the forefront of fighting against quishing attacks, taking a proactive stance in dissecting them to better protect our customers. Let’s delve into the mechanisms behind QR phishing, explore why QR codes are a preferred tool for attackers, and review how Cloudflare contributes to the fight against this evolving threat.
How quishing works
The impact of phishing and quishing are quite similar, as both can result in users having their credentials compromised, devices compromised, or even financial loss. They also leverage malicious attachments or websites to provide bad actors the ability to access something they normally wouldn’t be able to. Where they differ is that quishing is typically highly targeted and uses a QR code to further obfuscate itself from detection.
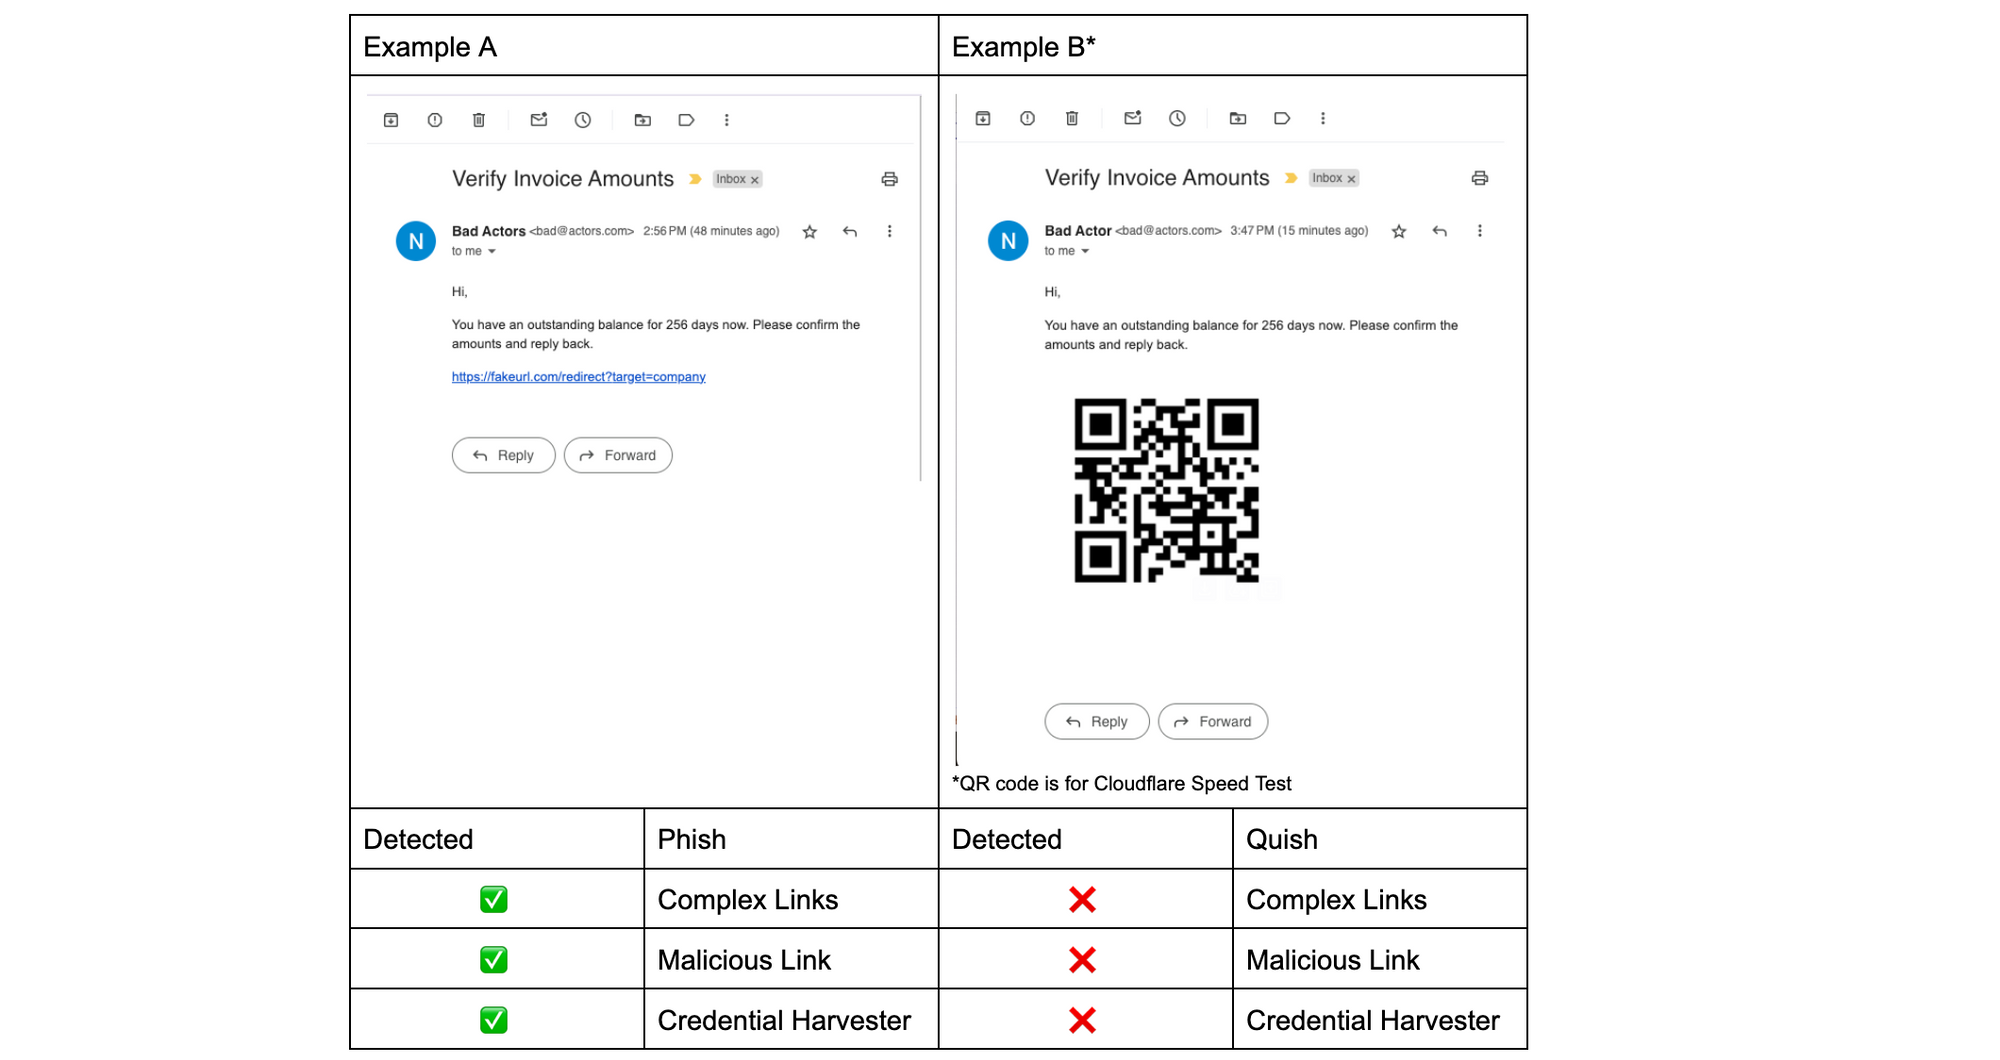
Since phish detection engines require inputs like URLs or attachments inside an email in order to detect, quish succeeds by hampering the detection of these inputs. In Example A below, the phish’s URL was crawled and after two redirects landed on a malicious website that automatically tries to run key logging malware that copies login names and passwords. For Example A, this clearly sets off the detectors, but Example B has no link to crawl and therefore the same detections that worked on Example A are rendered inert.
Strange you say, if my phone can scan that QR code then can’t a detection engine recognize the QR code as well? Simply put, no, because phish detection engines are optimized for catching phish, but to identify and scan QR codes requires a completely different engine – a computer vision engine. This brings us to why QR codes are a preferred tool for attackers.
Why QR codes for phishing?
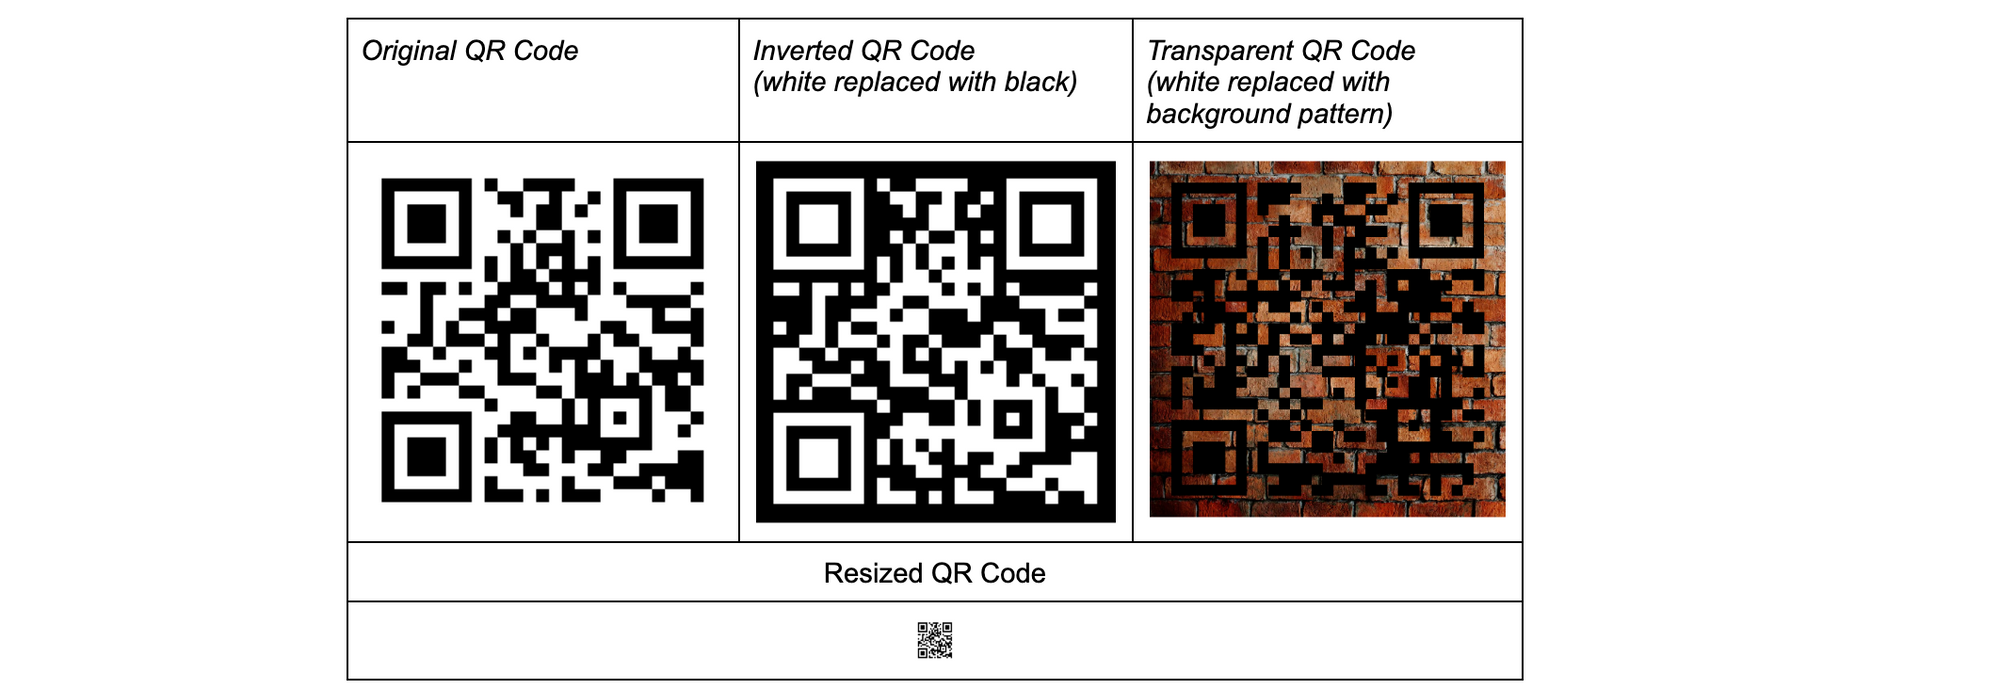
There are three main reasons QR codes are popular in phishing attacks. First, QR codes boast strong error correction capabilities, allowing them to withstand resizing, pixel shifting, variations in lighting, partial cropping, and other distortions. Indeed, computer vision models can scan QR codes, but identifying which section of an email, image, or webpage linked in an email has a QR code is quite difficult for a machine, and even more so if the QR codes have been obfuscated to hide themselves from some computer vision models. For example, by inverting them, blending them with other colors or images, or making them extremely small, computer vision models will have trouble even identifying the presence of QR codes, much less even being able to scan them. Though filters and additional processing can be applied to any image, not knowing what or where to apply makes the deobfuscation of a QR code an extremely expensive computational problem. This not only makes catching all quish hard, but is likely to cause frustration for an end user who won’t get their emails quickly because an image or blob of text looks similar to a QR code, resulting in delivery delays.
Even though computer vision models may have difficulty deobfuscating QR codes, we have discovered from experience that when a human encounters these obfuscated QR codes, with enough time and effort, they are usually able to scan the QR code. By doing everything from increasing the brightness of their screen, to printing out the email, to resizing the codes themselves, they can make a QR code that has been hidden from machines scan successfully.
Don’t believe us? Try it for yourself with the QR codes that have been obfuscated for machines. They all link to https://blog.cloudflare.com/
If you scanned any of the example QR codes above, you have just proven the next reason bad actors favor quish. The devices used for accessing QR codes are typically personal devices with a limited security posture, making them susceptible to exploitation. While secured corporate devices typically have measures to warn, stop, or sandbox users when they access malicious links, these protections are not available natively on personal devices. This can be especially worrisome, as we have seen a trend towards custom QR codes targeting executives in organizations.
QR codes can also be seamlessly layered in with other obfuscation techniques, such as encrypted attachments, mirrors that mimic well-known websites, validations to prove you are human before malicious content is revealed, and more. This versatility makes them an attractive choice for cybercriminals seeking innovative ways to deceive unsuspecting users by adding QR codes to previously successful phishing vectors that have now been blocked by security products.
Cloudflare’s protection strategy
Cloudflare has been at the forefront of defending against quishing attacks. We employ a multi-faceted approach, and instead of focusing on archaic, layered email configuration rules, we have trained our machine learning (ML) detection models on almost a decade’s worth of detection data and have a swath of proactive computer vision models to ensure all of our customers start with a turnkey solution.
For quish detections, we break it into two parts: 1) identification and scanning of QR codes 2) analysis of decoded QR codes.
The first part is solved by our own QR code detection heuristics that inform how, when, and where for our computer vision models to execute. We then leverage the newest libraries and tools to help identify, process, and most importantly decode QR codes. While it is relatively easy for a human to identify a QR code, there is almost no limit to how many ways they can be obfuscated to machines. The examples we provided above are just a small sample of what we’ve seen in the wild, and bad actors are constantly discovering new methods to make QR codes hard to quickly find and identify, making it a constant cat and mouse game that requires us to regularly update our tools for the trending obfuscation technique.
The second part, analysis of decoded QR codes, goes through all the same treatment we apply to phish and then some. We have engines that deconstruct complex URLs and drill down to the final URL, from redirect to redirect, whether they are automatic or not. Along the way, we scan for malicious attachments and malicious websites and log findings for future detections to cross-reference. If we encounter any files or content that are encrypted or password protected, we leverage another group of engines that attempt to decrypt and unprotect them, so we can identify if there was any obfuscated malicious content. Most importantly, with all of this information, we continuously update our databases with this new data, including the obfuscation of the QR code, to make better assessments of similar attacks that leverage the methods we have documented.
However, even with a well-trained suite of phish detection tools, quite often the malicious content is at the end of a long chain of redirects that prevent automated web crawlers from identifying anything at all, much less malicious content. In between redirects, there might be a hard block that requires human validation, such as a CAPTCHA, which makes it virtually impossible for an automated process to crawl past, and therefore unable to classify any content at all. Or there might be a conditional block with campaign identification requirements, so if anyone is outside the original target’s region or has a web browser and operating system version that doesn’t meet the campaign requirements, they would simply view a benign website, while the target would be exposed to the malicious content. Over the years, we have built tools to identify and pass these validations, so we can determine malicious content that may be there.
However, even with all the technologies we’ve built over the years, there are cases where we aren’t able to easily get to the final content. In those cases, our link reputation machine learning models, which have been trained on multiple years of scanned links and their metadata, have proven to be quite valuable and are easily applied after QR codes are decoded as well. By correlating things like domain metadata, URL structure, URL query strings, and our own historical data sets, we are able to make inferences to protect our customers. We also take a proactive approach and leverage our ML models to tell us where to hunt for QR codes, even if they aren’t immediately obvious, and by scrutinizing domains, sentiment, context, IP addresses, historical use, and social patterns between senders and recipients, Cloudflare identifies and neutralizes potential threats before they can inflict harm.
Creative examples and real world instances
With the thousands of QR codes we process daily, we see some interesting trends. Notable companies, including Microsoft and DocuSign, have frequently been the subjects of impersonation for quishing attacks. What makes this more confusing for users, and even more likely to scan them, is that these companies actually use QR codes in their legitimate workflows. This further underscores the urgency for organizations to fortify their defenses against this evolving threat.
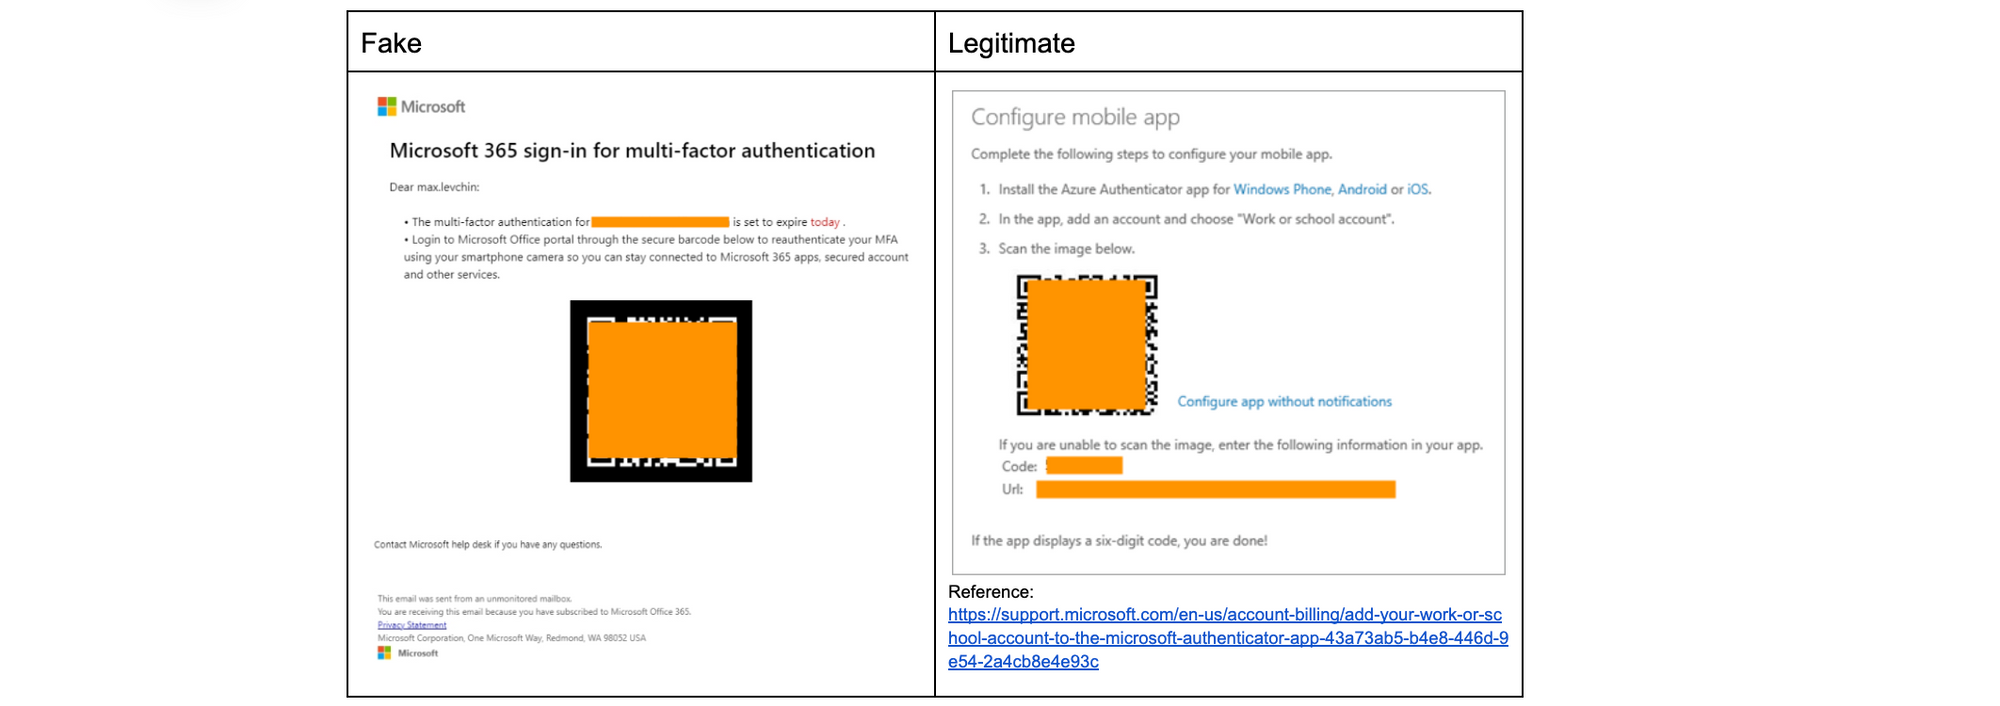
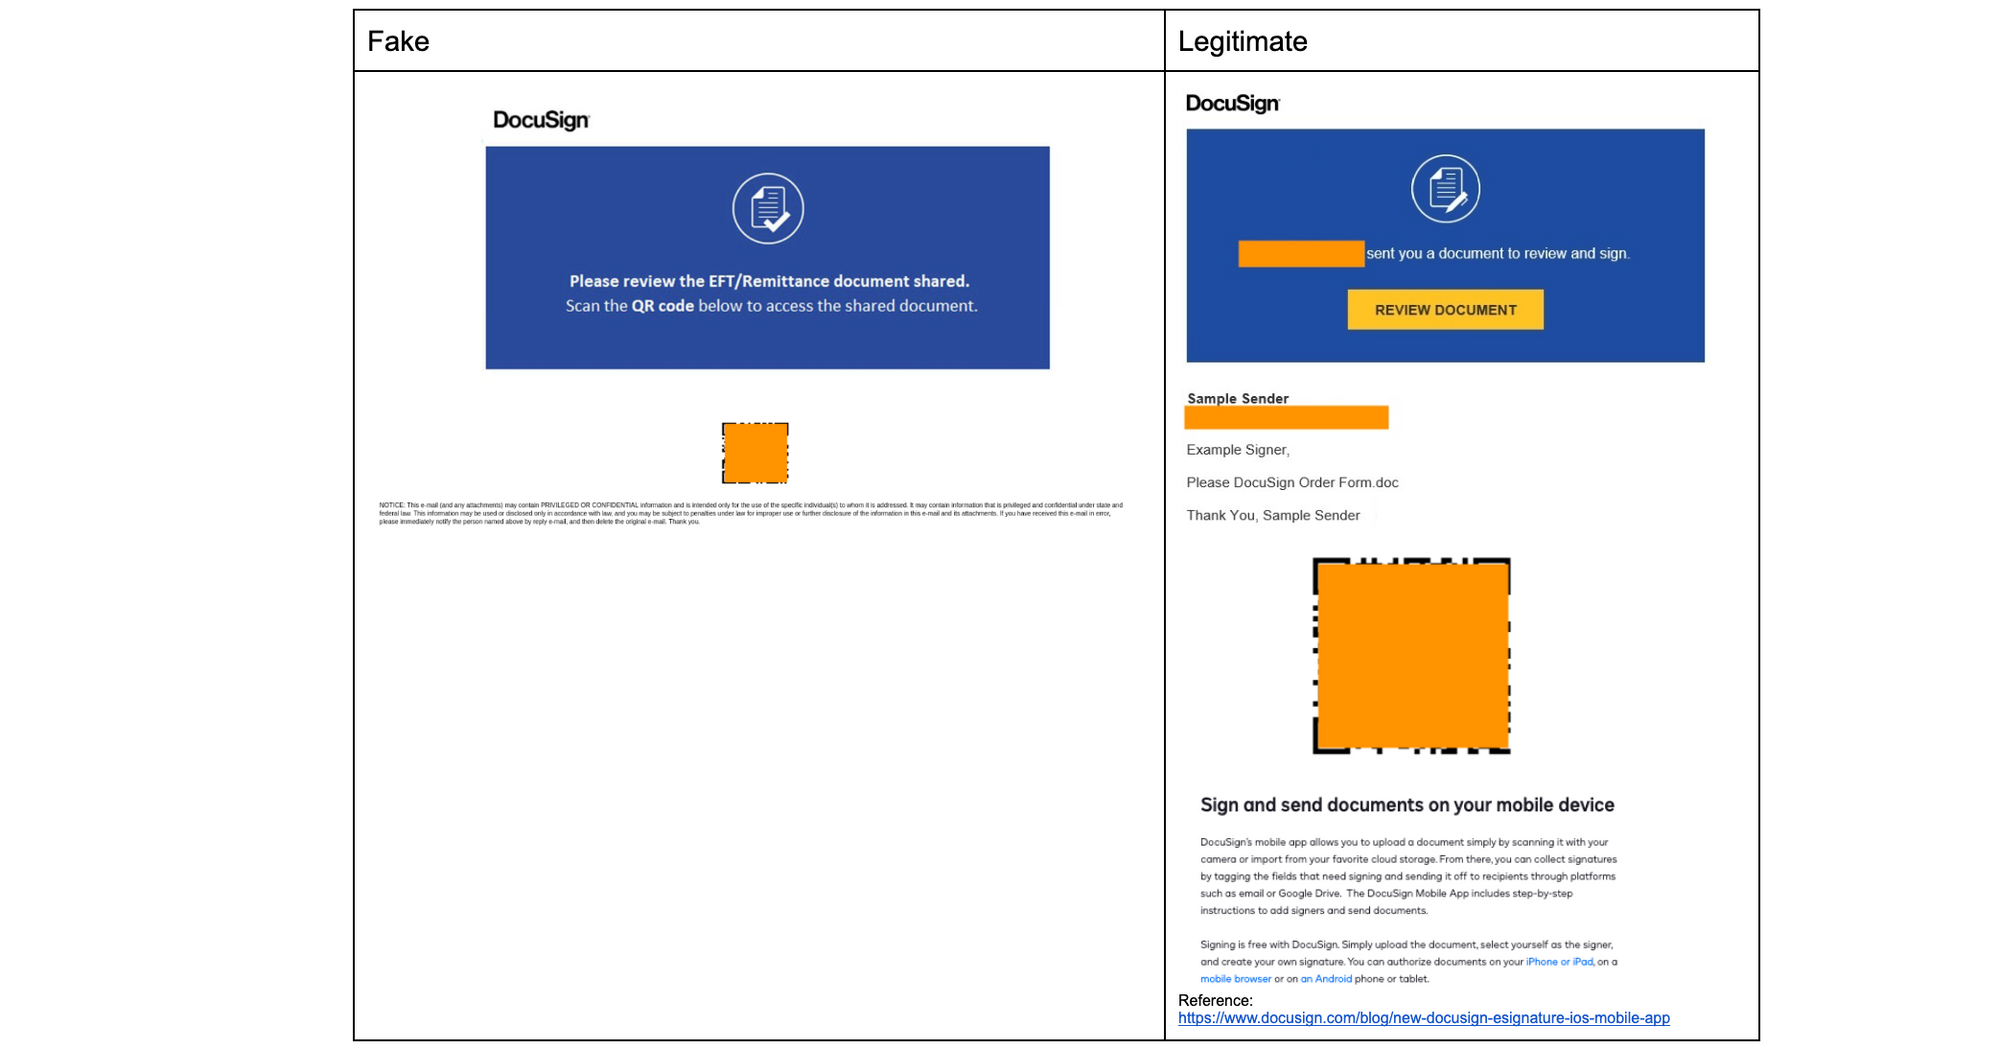
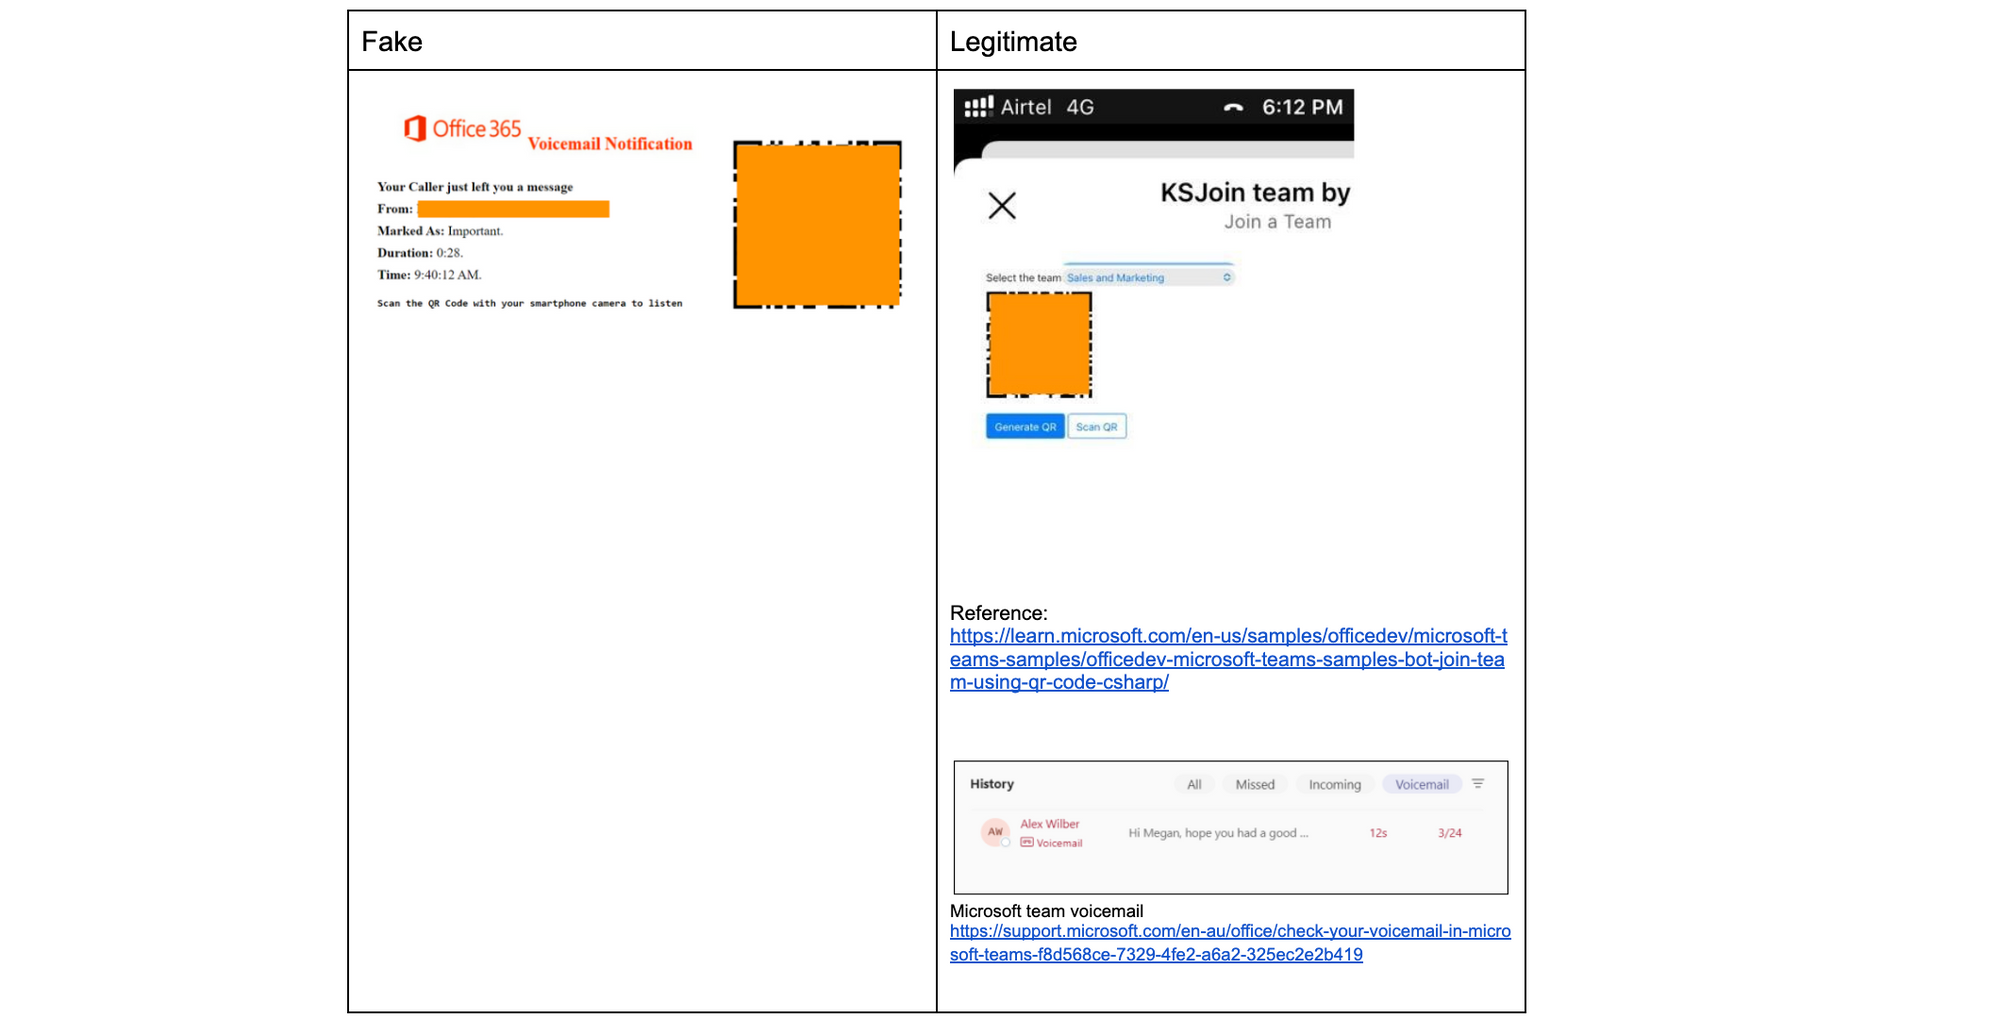
Below are three examples of the most interesting quish we have found and compared against the real use cases by the respective companies. The QR codes used in these emails have been masked.
Microsoft Authenticator
Microsoft uses QR codes as a faster way to complete MFA instead of sending six digit SMS codes to users’ phones that can be delayed and are also considered safer, as SMS MFA can be intercepted through SIM swap attacks. Users would have independently registered their devices and would have previously seen the registration screen on the right, so receiving an email that says they need to re-authenticate doesn’t seem especially odd.
DocuSign
DocuSign uses QR codes to make it easier for users to download their mobile app tosign documents, identity verification via a mobile device to take photos, and supports embedding DocuSign features in third party apps which have their own QR code scanning functionality. The use of QR codes in native DocuSign apps and non-native apps makes it confusing for frequent DocuSign users and not at all peculiar for users that rarely use DocuSign. While the QR code for downloading the DocuSign app is not used in signature requests, to a frequent user, it might just seem like a fast method to open the request in the app they already have downloaded on their mobile device.
Microsoft Teams
Microsoft uses QR codes for Teams to allow users to quickly join a team via a mobile device, and while Teams doesn’t use QR codes for voicemails, it does have a voicemail feature. The email on the left seems like a reminder to check voicemail in Teams and combines the two real use cases on the right.
How you can help prevent quishing
As we confront the persistent threat of quishing, it’s crucial for individuals and organizations to be vigilant. While no solution can guarantee 100% protection, collective diligence can significantly reduce the risk, and we encourage collaboration in the fight against quishing.
If you are already a Cloud Email Security customer, we remind you to submit instances of quish from within our portal to help stop current threats and enhance the capabilities of future machine learning models, leading to more proactive defense strategies. If you aren’t a customer, you can still submit original quish samples as an attachment in EML format to [email protected], and remember to leverage your email security provider’s submission process to inform them of these quishing vectors as well.
The battle against quishing is ongoing, requiring continuous innovation and collaboration. To support submissions of quish, we are developing new methods for customers to provide targeted feedback to our models and also adding additional transparency to our metrics to facilitate tracking a variety of vectors, including quish.
The PCI Security Standards Council (PCI SSC) is a global forum that connects stakeholders from the payments and payment processing industries to craft and facilitate adoption of data security standards and relevant resources that enable safe payments worldwide.
According to the PCI SSC website, “PCI Security Standards are developed specifically to protect payment account data throughout the payment lifecycle and to enable technology solutions that devalue this data and remove the incentive for criminals to steal it. They include standards for merchants, service providers, and financial institutions on security practices, technologies and processes, and standards for developers and vendors for creating secure payment products and solutions.”
Perhaps the most recognizable standard from PCI, their Data Security Standard (PCI DSS), is a global standard that provides a baseline of technical and operational requirements designed to protect account data. In March 2022, PCI SSC published version v4.0 of the standard, which replaces version v3.2.1. The updated version addresses emerging threats and technologies and enables innovative methods to combat new threats. This post will cover the changes to the standard that came with version 4.0 along with a high-level overview of how Rapid7 helps teams ensure their cloud-based applications can effectively implement and enforce compliance.
What’s New With Version 4.0, and Why Is It Important Now?
So, why are we talking about the new standard nearly two years after it was published? That’s because when the standard was published there was a two year transition period for organizations to adopt the new version and implement required changes that came with v4.0. During this transition period, organizations were given the option to assess against either PCI DSS v4.0 or PCI DSS v3.2.1.
For those that haven’t yet made the jump, the time is now This is because the transition period concluded on March 31, 2024, at which time version 3.2.1 was retired and organizations seeking PCI DSS certification will need to adhere to the new requirements and best practices. Important to note, there are some requirements that have been “future-dated.” For those requirements, organizations have been granted another full year, with those updates being required by March 31, 2025.
The changes were driven by direct feedback from organizations across the global payments industry. According to PCI, more than 200 organizations provided feedback to ensure the standard continues to meet the complex, ever-changing landscape of payment security.
Key changes for this version update include:
Flexibility in How Teams Achieve Compliance / Customized Approach
A primary goal for PCI DSS v4.0 was to provide greater flexibility for organizations in how they can achieve their security objectives. PCI DSS v4.0 introduces a new method – known as the Customized Approach – by which organizations can implement and validate PCI DSS controls Previously, organizations had the option of implementing Compensating controls, however these are only applicable when a situation arises whereby there is a constraint – such as legacy systems or processes – impacting the ability to meet a requirement.
PCI DSS v4.0 now provides organizations the means to choose to meet a requirement leveraging other means than the stated requirement. Requirement 12.3.2 and Appendices D and E outline the customized approach and how to apply it. To support customers, Rapid7’s new PCI DSS v4.0 compliance pack provides a greater number of insights than in previous iterations. This should lead to increased visibility and refinement in the process of choosing to mitigate and manage requirements.
A Targeted Approach to Risk Management
Alongside the customized approach concept, one of the most significant updates is the introduction of targeted risk analysis (TRA). TRAallows organizations to assess and respond to risks in the context of an organization’s specific operational environment. The PCI council has published guidance “PCI DSS v4 x: Targeted Risk Analysis Guidance” that outlines the two types of TRAs that an entity can employ regarding frequency of performing a given control and the second addressing any PCI DSS requirement for when an entity utilizes a customized approach.
To assist in understanding and having a consolidated view of security risks in their cloud environments, Rapid7 customers can leverage InsightCloudSec Layered Context and the recently introduced Risk Score feature. This feature combines a variety of risk signals, assigning a higher risk score to resources that suffer from toxic combinations or multiple risk vectors.Risk score holistically analyzes the risks that compound and increase the likelihood or impact of compromise.
Enhanced Validation Methods & Procedures
PCI DSS v4.0 has provided improvements to the self-assessment (SAQ) document and to the Report on Compliance (RoC) template, increasing alignment between them and the information summarized in an Attestation of Compliance to support organizations in their efforts when self-attesting or working with assessors to increase transparency and granularity.
New Requirements
PCI DSS v4.0 has brought with it a range of new requirements to address emerging threats. With modernization of network security controls, explicit guidance on cardholder data protections, and process maturity, the standard focuses on establishing sustainable controls and governance. While there are quite a few updates – which you can find detailed here on the summary of changes – let’s highlight a few of particular importance:
Multifactor authentication is now required for all access into the Cardholder Data Environment (CDE) – req. 8.5.1
Encryption of sensitive authentication data (SAD) – req. 3.3.3
New password requirements and updated specific password strength requirements: Passwords must now consist of 12 characters with special characters, uppercase and lowercase – reqs. 8.3.6 and 8.6.3
Access roles and privileges are based on least privilege access (LPA), and system components operate using deny by default – req. 7.2.5
Audit log reviews are performed using automated mechanisms – req. 10.4.1.1
These controls place role-based access control, configuration management, risk analysis and continuous monitoring as foundations, assisting organizations to mature and achieve their security objectives. Rapid7 can help with implementing and enforcing these new controls, with a host of solutions that offer PCI-related support – all of which have been updated to align with these new requirements.
How Rapid7 Supports Customers to Attain PCI DSS v4.0 Compliance
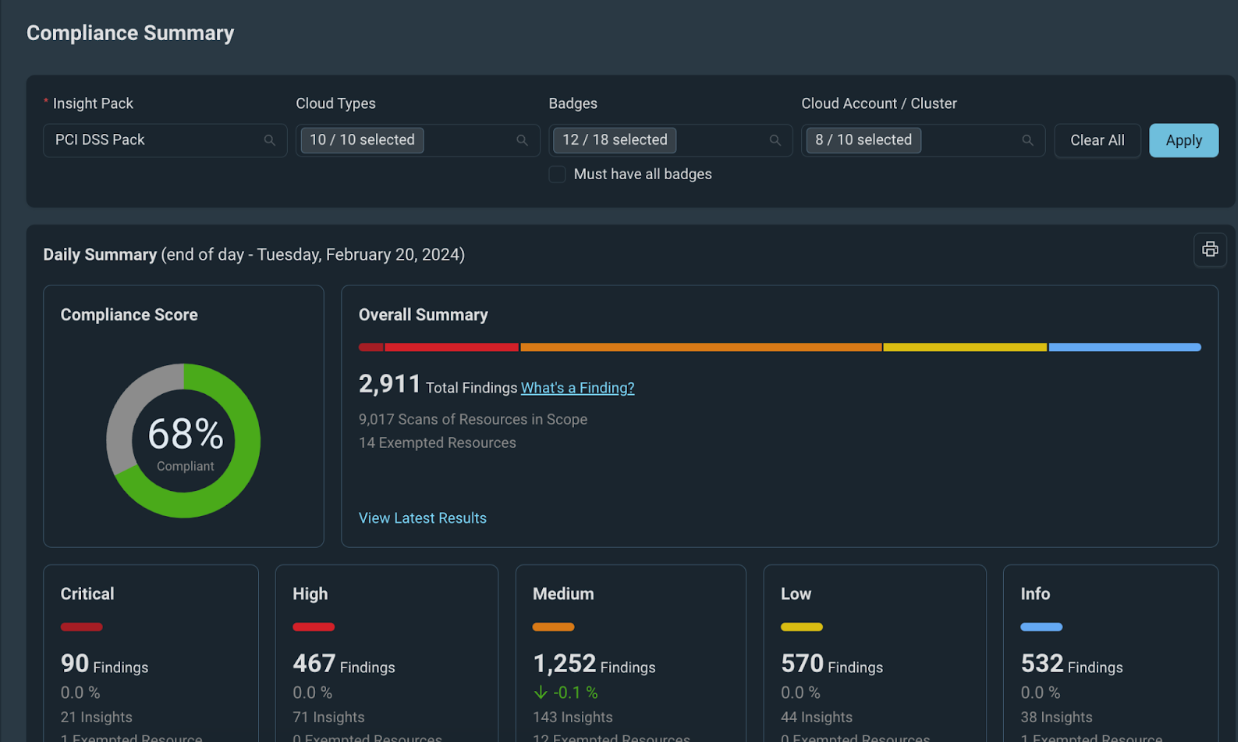
InsightCloudSec allows security teams to establish, continuously measure, and illustrate compliance against organizational policies. This is accomplished via compliance packs, which are sets of checks that can be used to continuously assess your entire cloud environment – whether single or multi-cloud. The platform comes out of the box with dozens of compliance packs, including a dedicated pack for the PCI DSS v4.0.
InsightCloudSec assesses your cloud environments in real-time for compliance with the requirements and best practices outlined by PCI It also enables teams to identify, assess, and act on noncompliant resources when misconfigurations are detected. If you so choose, you can make use of the platform’s native, no-code automation to remediate the issue the moment it’s detected, whether that means alerting relevant resource owners, adjusting the configuration or permissions directly or even deleting the non-compliant resource altogether without any human intervention. Check out the demo to learn more about how InsightCloudSec helps continuously and automatically enforce cloud security standards.
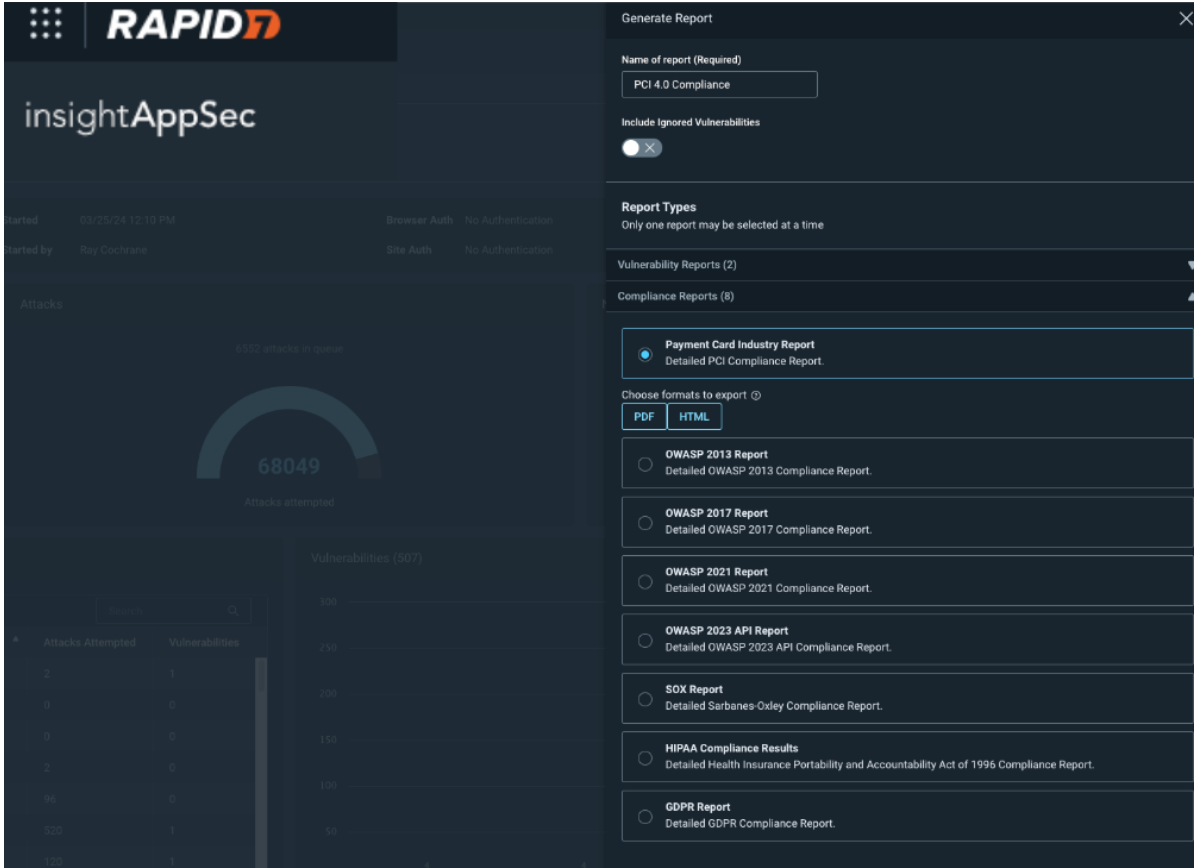
InsightAppSec also enables measurement against PCI v4.0 requirements to help you obtain PCI compliance. It allows users to create a PCI v4.0 report to help prepare for an audit, assessment or a questionnaire around PCI compliance. The PCI report gives you the ability to uncover potential issues that will affect the outcome or any of these exercises. Crucially, the report allows you to take action and secure critical vulnerabilities on any assets that deal with payment card data. PCI compliance auditing comes out of the box and is simple to generate once you have completed a scan against which to run the report.
InsightAppSec achieves this coverage by cross referencing and then mapping our suite of 100+ attack modules against PCI requirements, identifying which attacks are relevant to particular requirements and then attempting to exploit your application with those attacks to obtain areas where your application may be vulnerable. Those vulnerabilities are then packaged up in the PCI 4.0 report where you can see vulnerabilities listed by PCI requirements This provides you with crucial insights into any vulnerabilities you may have as well as enabling management of those vulnerabilities in a simplistic format.
For InsightVM customers, an important change in the revision is the need to perform authenticated internal vulnerability scans for requirement 11.3.1.2. Previous versions of the standard allowed for internal scanning without the use of credentials, which is no longer sufficient. For more details see this blog post.
Rapid7 provides a wide array of solutions to assist you in your compliance and governance efforts. Contact a member of our team to learn more about any of these capabilities or sign up for a free trial.
Security updates have been issued by Debian (apache2 and cockpit), Fedora (firefox, kernel, mbedtls, python-cbor2, wireshark, and yyjson), Mageia (nghttp2), Red Hat (kernel, kernel-rt, opencryptoki, pcs, shim, squid, and squid:4), Slackware (firefox), SUSE (emacs, firefox, and kernel), and Ubuntu (linux-aws, linux-aws-5.15, linux-aws-6.5, linux-raspi, and linux-iot).
След 4 одини проблеми с водата, най-накрая местните жители на Брестовица напипаха правилния начин за решаването на този пробем и той е ПРОТЕСТИ.
Ако обаче не знаем какъв е зародиша на проблема, да се скъсаме от протести, решение няма да има. Затова ще опиша основните точки, които имат отношение към решаването на проблема с водата на Брестовица.
Става въпрос за пари
Тук всички ще отбележат, че е много ясно, но да Ви кажа за какви конкретно пари става въпрос.
Без да съм хидроинженер, мога доста точно да предположа, че на село като Бретовица, подмяната на тръбите би струвало около 30 милиона лева. Поне на подобни села в други общини на които съм съдействал за финансиане беше толкова. Брестовица е доста по-голямо и затова съм завишил, но предполагам неоходимата сума е близка до тази.
Откъде може да дойдат тези пари?
Имайте предвид, че бюджета на Община Родопи е 52 млн лева. Тук влизат всички раходи, включтелно новата служебна кола на кмета на общината, новите фотоапарати за отразяване на ПР акциите, но също така и заплатите на учителите и закуските на деата в училище. Това е цялата сума.
Отделно предизборно беше теглен кредит от 7 млн лева.
Акцентирам на кредита, тъйкато той се прибавя към съществуващия вече такъв, което отрязва най-естествената възможност за финансиране на подмяната на тръбите на Брестовица, а именно финансиране чрез кредит.
Искам да припомня, че голяма част от кредита от 7 млн беше похарчен за други села или за разходи, покривани безплатно по Програмата за възстановяване и устойчивост. Нали помните каква еуфория и гордост настана след смяната на осветлението на селата? Беше отразено доста добре във ФБ и на страницата на всяко село от Община Родопи. Е тозно този разход нямаше смисъл да се прави, тъйкато се покриваха безплатно от въпросната Програма за възстановяване и устойчивост. И тук идва следващия проблем.
Общината няма капацитет да усвоява средства по програми и европейски проекти.
Като казвам няма капацитет, разбирайте интелектуален. Демонстрирах го достатъчно добре с горния пример с осветлението. Вместо администрацията да седне и да напише проект за финансиране, те теглят кредит. Както се казва – Те толкова си могат!
Ако поглднете отчета за бюджета ще видите, че миналата година има заложени 500 000 лева приходи от европейски проекти и 0 лева изпълнени. Това значи, че няма нито един проект.
Друг е въпросът, че 500 000 приходи от проекти е нищо за една община. Примерно осветлението на омразния гр. Пловдив в който всички от администрацията на Община Родопи се надпреварват да купуват апартаменти, има улично осветление изградено по Норвежката програма. Не знам дали в нашата община са чували за тази програма, но поне в отчетите и плановете за бюджета не се виждат такива планове.
Да обобщя до тук
След изтегления и рададен на други села предизборно кредит, Община Родопи не може да изтегли нов за водоснабдителната мрежа на Брестовица.
От досегашната работа и финансовите отчети е видно, че по програма средства също няма как да бъдат отпуснати. И това вече 4 години.
Моля използвайте приложената форма за записване на час за среща
[contact-form-7]
Средства от държавния бюджет
Предвид това, че предходните 2 най естествени начини за финансиране са недостъпни за Община Родопи, помощ от централния бюджет явно остава единствения начин на финансиране. Това, което забелязвам обаче в принципа на работа на общинската администрация е кастовия принцип. „Ти не си от нашите и затова за теб няма“ или обратното – „Ти си гласувал за нас, ще видим какво можем да направим“.
На същия принцип стоят нещата и в държавата. Избраме си Бате Бойко и едни фирми печелят. Идват ППДБ и правят чистка в администрацията и назначават свои.
За съжаление този принцип съществува от „време оно“, а в повечето случаи дори работи. Поне докато се се изчерпат парите.
В нашия случай парите са изчерпани. Борим се да влизаме в монетарния съюз и бюджетния дефецит е много важен, а пари за други разходи НЯМА.
Защото населението на Община Родопи си избра кмет от БСП. Няма лошо, но когато стане въпрос за пари, а принципа в държавното управление е същия като в нашата община, то тогав ана кой кмет да дадеш 30 милиона? На кмета на БСП или на твоя си кмет, който е избран от твоята партия?
Пак казвам – не се сърдете на управляващите. Те работят по същия начин както нашата администрация. За едни села има, за други няма. Брестовица е селото за което вече 4 години няма. Сега кметицата е „на г-н Михайлов“, но пари пак няма, ЗАЩОТО ВЕЧЕ ВСИЧКИ КМЕТОВЕ СА НА Г-Н МИХАЙЛОВ.
А баницата е малка. Не става да се разпредели, пък и на кредит сме яли досега.
Въпреки всичко решение има
И хората от Брестовица го намират. От моя опит с администрацията на Родопи съм разбрал едно – приесняват се единствено от обединени групи хора и лош ПР. Ако има начин нещо да се случи, то тов аще бъде само следствие на протести. Като не Ви чува кмета Михайлов, прескочете го. Протестирайте пред Областната управа. Там не са от БСП и ще имат изгода да се намесят. Пишете на Областния, идват избори това ще му е дивидент. Викайте повече телевизии, пишете във ФБ, идвайте на заседания на общинския съвет и поставяйте исканията си.
Говорете със съседите си, обединете се и изисквайте. Пари в бюджета както казах няма, няма и скоро да има. Този път с „мазнене“ във Фейсбук няма да стане. Ясно е, че много хора свикнаха на подаяния от кмета, но идва момента в който трябва да изискваш полагащото ти се.
Обединете се с други хора със същите проблеми в Община Родопи. Примерно комитета в Белащица. Хората и до референдум стигнаха. Тогава много други им се смяха, а общината се опита да го осуети, но сега става въпрос за вашите деца.
Нма да стане от един път, но няма друг начин. Пасивността не води до нищо добро. Положението е такова, че с ръкопляскане на ПР постовете на г-н Михайлов във ФБ няма да се случи. “Пари си трябват”, а парите следват проектите или интересите. След последното гласуване, интересът към вас явно е спаднал. Щом от 4 години е този проблем и пак гласуваме за още от същото, значи проблем няма.
Идват избори, използвайте ги. Ако ли не, заредете се с още 4 години търпение. За който трябва вода има достатъчно.
Васил Кендов – финансист Моля използвайте приложената форма за записване на час за среща
[contact-form-7]
Широко разпространено в България (а и в други страни) е убеждението, че увеличаването на наказанията е превенция срещу престъпността. Затова след всяко тежко престъпление, станало водеща тема в новинарските емисии, се чуват гласове за промяна на Наказателния кодекс (НК) и по-тежки присъди. Някои изразяват носталгия по законите от времето на хан Крум, когато за кражба са се рязали крайници, а националпопулисти като председателя на „Възраждане“ Костадин Костадинов дори искат връщане на смъртното наказание.
Два проблема плюс един
Проблемите с това популярно убеждение са два. Първо, то не почива на реални факти. В изследването на историка Стефан Иванов „От кражби до убийства. Криминалните престъпления в България (1944–1989 г.)“ например се доказва, че въпреки ефективното изпълнение на смъртни присъди, умишлените убийства по времето на социализма са дори повече, отколкото в посттоталитарния период.
Второ, въпреки това въпросното убеждение стои в основата на не една и две законови промени. Не поради некадърност на законотворците, а от чист популизъм, достигащ шизофренни висини. Например през 2020 г. отзвукът от катастрофата, при която загина журналистът Милен Цветков, стана повод ГЕРБ да предложи увеличаване на наказанията в НК за шофьори, употребили алкохол или наркотици. Две седмици по-късно партията представи концепция за наказателната политика за пет години напред, в която се казва: „Статистиката ясно сочи, че повишаването на размерите на наказанията не води до намаляване на престъпността.“
Към тези проблеми се прибавя и трети, местен – правосъдната система в България не изпълнява основната си функция да гарантира справедливо правосъдие в съответствие със законите. В такъв случай какво значение има колко строги са те? След като някои извършители на престъпления няма да бъдат осъдени, каквото и да са направили, а някои жертви на престъпления няма да получат не само справедливост, а дори и защита.
Защо е важно да говорим за Владислава Цариградска
Ако правосъдната система не е в състояние да защити един съдия, който просто се опитва да работи както трябва, тя не може да защити никого. Пример за такъв съдия e Владислава Цариградска. Одисеята си тя обобщава в писмо, което на 12 април изпраща до членовете на Висшия съдебен съвет и председателката на Върховния касационен съд, както и до медии. Татяна Ваксберг го обобщава:
Съдийката твърди, че я заплашват със смърт, а хората, които трябва да я защитят, все едно не я чуват. И така пет години.
В този период от пет години, в който се сменят трима главни прокурори, Цариградска работи в Районния съд в Луковит, а след това – в Окръжния съд в Плевен. Първоначално я заплашват Мартин Божанов, известен като Нотариуса, и хора около него, защото тя отказва да решава дела така, както той иска, и да си направи отвод по тях. Божанов дори отправя заплахи към нея в съдебната зала.
Следва компроматна кампания срещу Цариградска първоначално в ПИК, но тъй като съдийката продължава да не се подчинява, компроматите се множат и из други от „пеевските“ медии. Същевременно тя получава и заплахи. През 2020 г. е под охрана за 6 месеца, но охраната си тръгва, а заплахите постоянстват. Цариградска търси правата си в съда, не я държат в течение по хода на делата ѝ, но пък сайтът „Афера“ публикува части от нейни показания – значи се е сдобил с тях от вътрешен на съда човек.
След убийството на Мартин Божанов заплахите не престават, а стават все повече (над 70) и все по-страшни – че ако не „млъкне“, ще ѝ изкормят гениталиите, че съпругът и трите ѝ деца „ще са с бетонирани крака на дъното на язовира“ и т.н. Полицията задържа клошар, който беше обвинен, че е изпращал анонимни заплахи и до различни институции. Тази версия не изглежда реалистична – най-малкото заради упоритата слепота на правосъдната система за случая на Цариградска. А и например защото предупреждение „да се кротне“ идва също от човек на име Веселин Иванов – бивш служител в Дирекция „Публична комуникация“ при главния прокурор.
От средата на февруари 2024 г. Цариградска отново е с охрана, но след смяната на правителството отговорна за охраната в Министерството на правосъдието става представителка на прокуратурата. А прокуратурата години наред упорито отказва да разследва заплахите срещу съдийката. В писмото си Цариградска иска мерки, които да осигурят защита и правото на честно правосъдие както за нея, така и за всеки съдия, който е в подобна ситуация.
Репресии срещу други съдии
Съчетанието от компроматна война и излагане на риск на „непослушни“ съдии не е прецедент, независимо на колко висока позиция се намират те. Лозан Панов, който беше председател на Върховния касационен съд между 2015 и 2020 г., беше редовен обект на компромати в „пеевските“ медии. В писмото си Владислава Цариградска припомня протеста срещу него през 2017 г., който се запомни с одраните агнешки главички. След години Любена Павлова – тогава бъдеща, а днес бивша съпруга на Петьо Петров, известен като Еврото – призна, че е организирала протеста по поръчка на Еврото, чието име нашумя покрай аферата „Осемте джуджета“.
Цариградска припомня и част от перипетиите на съдия Мирослава Тодорова. През 2021 г. Европейският съд по правата на човека (ЕСПЧ) осъди България заради дисциплинарни производства срещу съдийката в периода 2011–2012 г. Тя е уволнена през 2012 г., а през 2013 г. е възстановена на работа, но на по-ниска длъжност за една година.
Обвиненията срещу Тодорова са скалъпени, а истинската причина е, че по онова време тя е председателка на Съюза на съдиите в България – неправителствена организация, позволяваща си критични позиции по отношение на правосъдната система. През 2012 г. организацията излиза с остра реакция срещу назначаването на Владимира Янева за председател на Софийския градски съд. На следващия ден Мирослава Тодорова е уволнена.
Затова ЕСПЧ отсъжда, че по отношение на нея е нарушена Европейската конвенция за правата на човека, по силата на която, казано накратко, човек не може да бъде наказван по причини, различни от описаните в закона, по който е наказан. Обвиненията срещу Тодорова са, че бави делата си, но по същество „наложените ѝ санкции са представлявали намеса в упражняването на правото ѝ на свобода на изразяване“.
Янева впрочем също е уволнена през 2015 г. , а после – осъдена условно. Причината е, че е разрешавала незаконно подслушване. Името ѝ беше замесено в редица скандали, свързани с отношенията между политическата власт и прокуратурата – достатъчно е да си спомним за „опраскването“ и „двете каки“.
С това обаче репресиите срещу Мирослава Тодорова от страна на върховете на правосъдната система не престават. През 2019 г. Инспекторатът на Висшия съдебен съвет (ИВСС) публикува онлайн, както всяка година, имотните декларации на съдиите. От всички над 4400 декларации само тази на Тодорова е с незаличени лични данни. Така ЕГН-то, адресът и номерът на личната ѝ карта стават общодостъпни (включително за хората, които е осъдила), както и ЕГН-тата на нейния партньор и непълнолетния ѝ син – в противоречие със Закона за защита на личните данни.
Според ИВСС става въпрос за „пропуск“. Файлът с декларацията на Тодорова е озаглавен NE SE CHISTIIIIIIIIIIIIIIIIII, което навежда на мисълта, че съответната информация умишлено не е изчистена и ИВСС нарочно е изложил съдийката на риск.
Потребност от възстановително правосъдие
Освен че правосъдната система ги репресира, защото имат дързостта да работят съвестно и да имат високи професионални стандарти, между Владислава Цариградска и Мирослава Тодорова има още нещо общо – и двете застават зад принципите на възстановителното правосъдие. Това означава не просто извършителите на престъпление да бъдат наказани, а да имат възможност да компенсират поне отчасти стореното и да помогнат на жертвите.
„Това не значи някой да бъде освободен от отговорност, означава да се намесиш и да подпомогнеш след това съвместното живеене на хората“, разяснява Владислава Цариградска пред „Свободна Европа“. В статия за „Тоест“ съдиите Мирослава Тодорова и Калин Калпакчиев дефинират възстановителното правосъдие като „способ да видиш другия като пълноценно човешко същество“.
Да си представим правосъдна система, в която хората носят отговорност за престъпленията си, но тя не се свежда до изолиране от обществото и издевателства в затвора, а включва сериозни усилия за превъзпитание и възможност за компенсиране на щетите впоследствие.
В тази система Мартин Божанов не е оръжие за кални поръчки, докато стане неудобен и съответно бъде убит, а просто далавераджия и имотен измамник. След като е осъден и излежава намален срок на присъдата си, защото се съгласява да премине през рехабилитационна програма, той се свързва, с посредничеството на медиатор, със свои жертви и им помага. На единия прави ремонт в дома, който преди се е опитал незаконно да отнеме. На друг помага да си отвори кафене, понеже има опит в това. И той е жив и доволен от живота си, и потърпевшите са компенсирани, и правосъдната система си е свършила работата.
Ще си кажете: проблемът не е, че нямаме възстановително правосъдие, а че и това правосъдие, което имаме, не работи справедливо и не успява да гарантира справедливост дори за онези, които го практикуват. Прави сте, знам. От друга страна обаче, ако една система не функционира, може би трябва да бъде конструирана по друг начин. И след като по-строгите наказания така и така не дават желания ефект, защо да не пробваме с добро?
Водещо изображение: Владислава Цариградска в студиото на „Здравей, България“ по Нова телевизия
The Internet has a plethora of moving parts: routers, switches, hubs, terrestrial and submarine cables, and connectors on the hardware side, and complex protocol stacks and configurations on the software side. When something goes wrong that slows or disrupts the Internet in a way that affects your customers, you want to be able to localize and understand the issue as quickly as possible.
New Map The new Amazon CloudWatch Internet Weather Map is here to help! Built atop of collection of global monitors operated by AWS, you get a broad, global view of Internet weather, with the ability to zoom in and understand performance and availability issues that affect a particular city. To access the map, open the CloudWatch Console, expand Network monitoring on the left, and click Internet Monitor. The map appears and displays weather for the entire world:
The red and yellow circles indicate current, active issues that affect availability or performance, respectively. The grey circles represent issues that have been resolved within the last 24 hours, and the blue diamonds represent AWS regions. The map will automatically refresh every 15 minutes if you leave it on the screen.
Each issue affects a specific city-network, representing a combination of a location where clients access AWS resources, and the Autonomous System Number (ASN) that was used to access the resources. ASNs typically represent individual Internet Service Providers (ISPs).
The list to the right of the map shows active events at the top, followed by events that have been resolved in the recent past, looking back up to 24 hours:
I can hover my mouse over any of the indicators to see the list of city-networks in the geographic area:
If I zoom in a step or two, I can see that those city-networks are spread out over the United States:
I can zoom in even further and see a single city-network:
This information is also available programmatically. The new ListInternetEvents function returns up to 100 performance or availability events per call, with optional filtering by time range, status (ACTIVE or RESOLVED), or type (PERFORMANCE or AVAILABILITY). Each event includes full details including latitude and longitude.
The new map is accessible from all AWS regions and there is no charge to use it. Going forward, we have a lot of powerful additions on the roadmap, subject to prioritization based on your feedback. Right now we are thinking about:
Displaying causes of certain types of outages such as DDoS attacks, BGP route leaks, and issues with route interconnects.
Adding a view that is specific to a chosen ISP.
Displaying the impact to public SaaS applications.
Please feel free to send feedback on this feature to [email protected] .
CloudWatch Internet Monitor The information in the map applies to everyone who makes use of applications built on AWS. If you want to understand how internet weather affects your particular AWS applications and to take advantage of other features such as health event notification and traffic insights, you can make use of CloudWatch Internet Monitor. As my colleague Sébastien wrote when he launched this feature in late 2022:
You told us one of your challenges when monitoring internet-facing applications is to gather data outside of AWS to build a realistic picture of how your application behaves for your customers connected to multiple and geographically distant internet providers. Capturing and monitoring data about internet traffic before it reaches your infrastructure is either difficult or very expensive.
After you review the map, you can click Create monitor to get started with CloudWatch Internet Monitor:
After that you enter a name for your monitor, choose the AWS resources (VPCs, CloudFront distributions, Network Load Balancers, and Amazon WorkSpace Directories) to monitor, then select the desired percentage of internet-facing traffic to monitor. The monitor will begin to operate within minutes, using entries from your VPC Flow Logs, CloudFront Access Logs, and other telemetry to identify the most relevant city-networks.
Here are some resources to help you learn more about this feature:
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


 Bukhtawar Khan is a Principal Engineer working on Amazon OpenSearch Service. He is interested in building distributed and autonomous systems. He is a maintainer and an active contributor to OpenSearch.
 Gaurav Bafna is a Senior Software Engineer working on OpenSearch at Amazon Web Services. He is fascinated about solving problems in distributed systems. He is a maintainer and an active contributor to OpenSearch.
 Sachin Kale is a senior software development engineer at AWS working on OpenSearch.
 Rohin Bhargava is a Sr. Product Manager with the Amazon OpenSearch Service team. His passion at AWS is to help customers find the correct mix of AWS services to achieve success for their business goals.
 Ranjith Ramachandra is a Senior Engineering Manager working on Amazon OpenSearch Service. He is passionate about highly scalable distributed systems, high performance and resilient systems.


 Sandipan Bhaumik is a Senior Analytics Specialist Solutions Architect based in London, UK. He helps customers modernize their traditional data platforms using the modern data architecture in the cloud to perform analytics at scale.
 Sain Das is a Senior Product Manager on the Amazon Redshift team and leads Amazon Redshift GTM for partner programs, including the Powered by Amazon Redshift and Redshift Ready programs.


 The Internet has a plethora of moving parts: routers, switches, hubs, terrestrial and submarine cables, and connectors on the hardware side, and complex protocol stacks and configurations on the software side. When something goes wrong that slows or disrupts the Internet in a way that affects your customers, you want to be able to localize and understand the issue as quickly as possible.


