Tag Archives: Amazon EC2

How to migrate your Amazon EC2 Oracle Transparent Data Encryption database encryption keystore to AWS CloudHSM

Post Syndicated from Bhushan Bhale original https://aws.amazon.com/blogs/security/how-to-migrate-your-ec2-oracle-transparent-data-encryption-tde-database-encryption-wallet-to-cloudhsm/

July 30, 2025: This post has been republished to migrate the Amazon EC2 Oracle Transparent Data Encryption database encryption keystore to AWS CloudHSM using AWS CloudHSM Client SDK 5.


Encrypting databases is crucial for protecting sensitive data, helping you to be aligned with security regulations and safeguarding against data loss. Oracle Transparent Data Encryption (TDE) is a feature that you can use to encrypt data at rest within an Oracle database. TDE uses envelope encryption. Envelope encryption is when the encryption key used to encrypt the tables of your database is encrypted by a primary key that resides either in a software keystore or on a hardware keystore, such as a hardware security module (HSM). This primary key is non-exportable by design to protect the confidentiality and integrity of your database operation. This gives you a more granular encryption scheme on your data. Hence, TDE for Oracle is a common use case for HSM devices such as AWS CloudHSM.

Oracle TDE supports keystores to securely store the TDE primary encryption keys. You can use either the TDE wallet (software keystore) or external key managers such as an HSM device. In this solution, we show you how to migrate a TDE keystore for an Oracle 19c database installed on Amazon Elastic Compute Cloud (Amazon EC2) from a software-based TDE wallet to AWS CloudHSM.

Using an external key manager, such as CloudHSM, offers several benefits over keeping keys on the Oracle wallet on the host:

  • Enhanced security: CloudHSM provides FIPS 140 validated hardware security, keeping the encryption key in a tamper-resistant module.
  • Centralized key management: CloudHSM supports centralized management of encryption keys, making it straightforward to rotate, back up, and audit keys.
  • Compliance: Your regulatory requirements may include encryption, and using CloudHSM can help you meet these compliance needs.

When you move from one type of keystore to another, new TDE primary keys are created inside the new keystore. To make sure that you have access to backups that rely on your past encryption keys, consider leaving the keystore running for your normal recovery window period or copying existing keys to the new keystore with exact key labels. Being able to access prior primary keys will help avoid data re-encryption.

You can use TDE to encrypt data online or offline. Encrypting TDE tablespace online minimizes disruption to database operations; however, it requires twice the storage space as the tablespace being encrypted, because the encryption process happens on a copy of the original tablespace.

Solution overview

In this solution, you migrate a TDE keystore for an Oracle 19c database from a software-based TDE wallet to CloudHSM, using the steps shown in Figure 1. Start by moving the current encryption keystore, which is your original TDE wallet, to a software wallet. This is done by replacing the PKCS#11 provider of your original HSM with the CloudHSM PKCS#11 software library (steps 1–2), next you reverse migrate to a local wallet (steps 3–5). The third step is to switch the encryption wallet for your database to your CloudHSM cluster (steps 6 and 7). After this process is complete, your database will automatically re-encrypt the data keys using the new primary key.
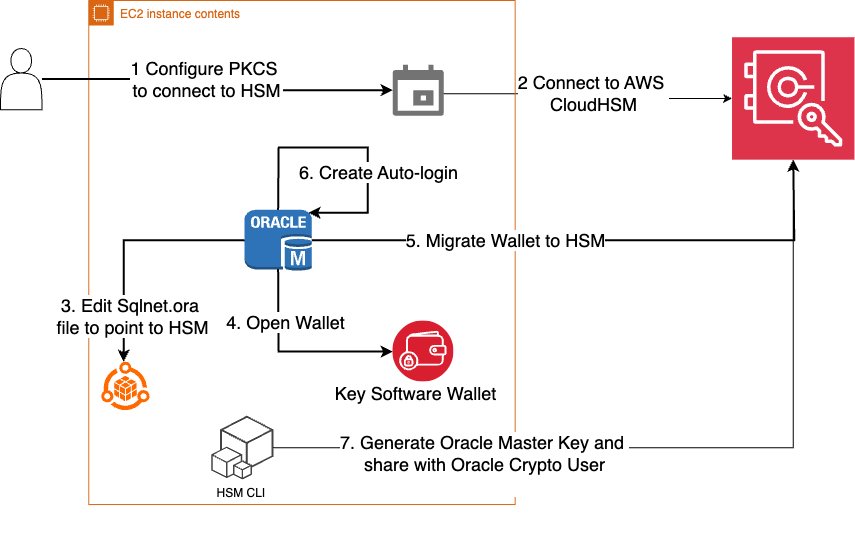
Figure 1: Steps to migrate your EC2 Oracle TDE database encryption wallet to CloudHSM

Figure 1: Steps to migrate your EC2 Oracle TDE database encryption wallet to CloudHSM

Note: The following instructions were tested using Oracle version 19c.

Prerequisites

You must have the following prerequisites in place to complete the solution in this post.

  • AWS CloudHSM cluster: You need to have a CloudHSM cluster set up and configured with an admin EC2 instance for interacting with CloudHSM following steps and best practices covered in Getting started with AWS CloudHSM.
  • Oracle database: Make sure that your Oracle database is up and running. This post assumes that you have an Oracle Database 19c database running on an EC2 Linux instance and there is network connectivity set up to CloudHSM as explained in this Configure the Client Amazon EC2 instance security groups for AWS CloudHSM.

Migrate an Oracle database keystore to a CloudHSM external keystore

As the first step in the migration, you need to migrate your Oracle database keystore to a CloudHSM external keystore. You do this by installing the CloudHSM client and the PKCS#11 library and then configuring the PKCS#11 library to connect to the HSM cluster.

Install the CloudHSM client:

  1. Install the latest CloudHSM client software on your EC2 instance.
  2. Configure the client to connect to HSMs in your cluster. For Linux EC2, use the following command:
    sudo /opt/cloudhsm/bin/configure-cli -a <The ENI IPv4 / IPv6 addresses of the HSM>
    

  3. Copy the CloudHSM issuing certificate created when you initialized the cluster (customerCA.crt) to the /opt/cloudhsm/etc folder. For more information, see Activate the cluster in AWS CloudHSM.
  4. Validate connectivity to the CloudHSM cluster.
    /opt/cloudhsm/bin/cloudhsm-cli interactive
    

  5. Sign in to the cluster as admin and create a crypto user (e.g. hsm-crypto-user) and assign it the role crypto-user.
    aws-cloudhsm > login --username hsm-crypto-user --role admin
    aws-cloudhsm > user create --username hsm-crypto-user --role crypto-user
    

  6. Sign in as hsm-crypto-user and validate the configuration


Install the PKCS#11 Library

  1. Install the PKCS #11 library for AWS CloudHSM Client SDK 5.
  2. Configure Oracle to use the PKCS library:
    1. Copy the PKCS#11 library to the appropriate Oracle folder. Typically, this is:
           cp /opt/cloudhsm/libcloudhsm_pkcs11.so /opt/oracle/extapi/[32,64]/hsm/aws/{VERSION}/libcloudhsm_pkcs11.so
      

    2. Make sure that the folder /opt/oracle has the correct ownership, usually oracle:dba as owner:group.

Configure PKCS#11 library to connect to the HSM cluster

Use the following commands:

  1. sudo /opt/cloudhsm/bin/configure-pkcs11 -a <HSM IP addresses>
  2. sudo /opt/cloudhsm/bin/configure-pkcs11 --hsm-ca-cert <customerCA certificate file>

Configure the Oracle wallet location

In this section, you configure Oracle to point to CloudHSM using the sqlnet.ora file.

To configure the Oracle wallet location:

  1. Edit the sqlnet.ora parameter ENCRYPTION_WALLET_LOCATION to point to the HSM:
    ENCRYPTION_WALLET_LOCATION=
      (SOURCE=(METHOD=HSM)
      )
    

  2. Verify that the WALLET_ROOT parameter is pointing to the current file-based TDE wallet location. This parameter defines the location where the TDE wallet (and other related files) will be stored. You can set it to an existing directory, preferably one in your $ORACLE_BASE or $ORACLE_HOME directory, but other locations are also possible.
    show parameter wallet_root
    show parameter tde_configuration
    

  3. Use the following commands to set WALLET_ROOT if it hasn’t already been set.
    ALTER SYSTEM SET WALLET_ROOT = '/u01/app/oracle/admin/orcl/wallet' SCOPE=BOTH SID='*';
    ALTER SYSTEM SET TDE_CONFIGURATION=“KEYSTORE_CONFIGURATION=FILE” SCOPE=BOTH SID=“*”
    

Note:

  • In Oracle Database 19c and later, the ENCRYPTION_WALLET_LOCATION. parameter in sqlnet.ora is deprecated in favor of using WALLET_ROOT and TDE_CONFIGURATION.
  • You can also use the V$ENCRYPTION_WALLET view to check the current keystore location and status.

Point the Oracle database to use a local file-based keystore and CloudHSM

The KEYSTORE_CONFIGURATION attribute within TDE_CONFIGURATION determines the keystore type.

To point the Oracle database:

  1. Use the following code to point the database to the local keystore and CloudHSM.
    ALTER SYSTEM SET TDE_CONFIGURATION="KEYSTORE_CONFIGURATION=HSM|FILE" SCOPE = BOTH SID = '*'; 
    

  2. Restart the database to have consistent results.

Verify that the keystore file-based wallet is open

To proceed with encryption key migration, you need to check the current keystore status and make sure that the file-based wallet is open.

To verify that the wallet is open:

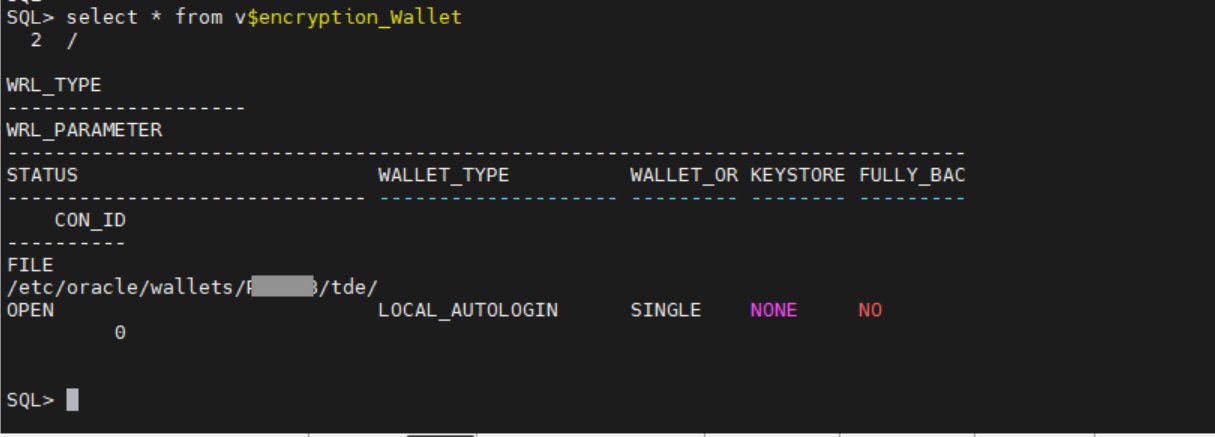
  1. Check to see if the file-based wallet is open.
    Select * from V$encryption_wallet;
    

    Figure 2: Verify that the wallet status is OPEN

    Figure 2: Verify that the wallet status is OPEN

  2. If the wallet status is not OPEN, use the following command to open it:
      ALTER SYSTEM SET ENCRYPTION WALLET OPEN IDENTIFIED BY "wallet_password";
    

Migrate the encryption key to CloudHSM

Use the ADMINISTER KEY MANAGEMENT SET ENCRYPTION KEY command to initiate the TDE primary encryption key migration.

To migrate the encryption key:

  • Use the following command to migrate the encryption key:
    ADMINISTER KEY MANAGEMENT SET ENCRYPTION KEY IDENTIFIED BY "hsm-crypto-user:password" MIGRATE USING "wallet-password" WITH BACKUP USING 'backup_tag';
    

The parameters used to migrate the encryption key are:

  • SET ENCRYPTION KEY: Specifies that the command is related to the TDE primary encryption key
  • IDENTIFIED BY: Specifies the details for migrating the keystore, including the external keystore user and password
  • MIGRATE USING: Specifies the password for the file-based wallet containing the primary encryption key
  • WITH BACKUP: Creates a backup of the keystore before the migration

Verify that the migration is complete

At this point, the migration from Oracle to Cloud HSM should be complete. Use the following steps to verify it.

To verify the migration:

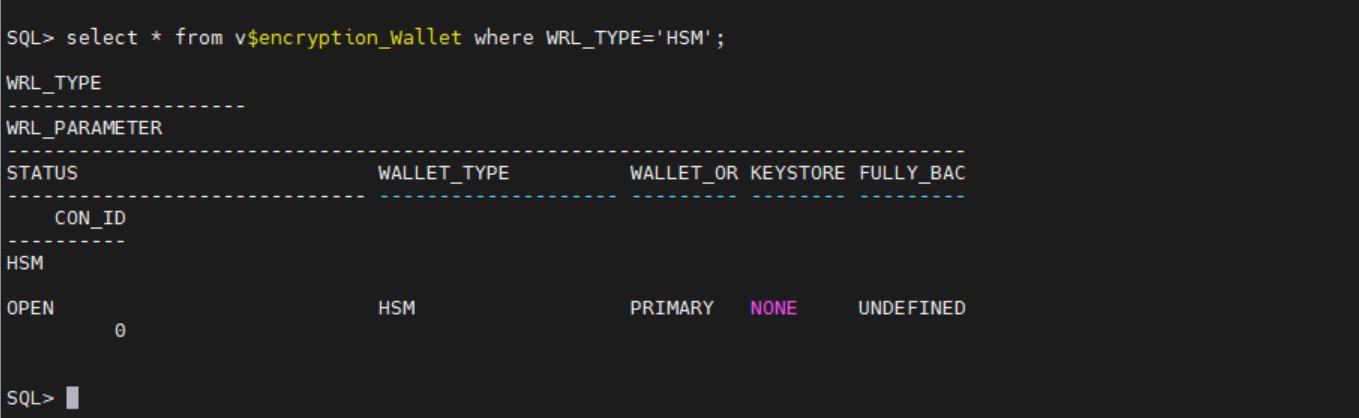
  1. Check the wallet status again. If the migration was successful, the WALLET_TYPE will be HSM and the WALLET_OR will be PRIMARY.
    Select * from V$encryption_wallet;
    

    Figure 3: Verify that WALLET_TYPE and WALLET_OR are correct

    Figure 3: Verify that WALLET_TYPE and WALLET_OR are correct

  2. In the wallet is not open, use:
    SQL>administer key management set keystore open identified by "hsm-crypto-user:password"
    

  3. Verify that the database can access encrypted data without issues, confirming that the migration was successful.
Setup auto-login

Create auto-login to open the wallet during database restarts to connect to AWS CloudHSM.

To set up auto_login:

  1. Create a new file-based keystore with the same username and password as the CloudHSM crypto user.
    ADMINISTER KEY MANAGEMENT CREATE KEYSTORE '/etc/oracle/wallets/<path>/tde' IDENTIFIED BY "hsm-crypto-user:password";
    

  2. Add the CloudHSM crypto user password to a keystore (TDE wallet).
    ADMINISTER KEY MANAGEMENT ADD SECRET 'hsm-crypto-user:password' FOR CLIENT 'HSM_PASSWORD' TO KEYSTORE '/etc/oracle/wallets/<path>/tde' IDENTIFIED BY "hsm-crypto-user:password" WITH BACKUP;
    

  3. The following command creates a new auto-login keystore. This is useful for scenarios where the keystore needs to be accessed without human intervention.
    ADMINISTER KEY MANAGEMENT CREATE AUTO_LOGIN KEYSTORE FROM KEYSTORE '/etc/oracle/wallets/<path>/tde' IDENTIFIED BY "<hsm-crypto-user:password>";
    

  4. Open the newly created file based keystore.
    ADMINISTER KEY MANAGEMENT SET KEYSTORE OPEN IDENTIFIED BY "<hsm-crypto-user:password>" 
    

Key rotation

Key rotation helps you to adhere to security best practices by providing several data security benefits. Regular rotation of TDE keys reduces the window of opportunity for a bad actor who might have obtained a key, thereby minimizing the impact of a potential breach.

Many established security frameworks and compliance standards—such as PCI DSS and HIPAA—recommend or require regular key rotation to maintain the integrity and confidentiality of encrypted data. By making sure that keys aren’t used indefinitely, you can help reduce the risk of exposure or compromise, which reinforces overall security.

Encryption algorithms can become less secure over time because of advancements in computing power or newly discovered vulnerabilities. By rotating keys regularly, you can transition to stronger encrypting methods as needed, and so improve protection against emerging risks.

When to rotate TDE keys

The frequency of key rotation depends on several factors, including organizational policies, regulatory requirements, and the sensitivity of the data being protected. Here are some common practices:

  • Annually: Many organizations rotate TDE keys once a year to align with common compliance requirements.
  • Quarterly: For higher-security environments or more sensitive data, rotating keys every quarter can provide an additional layer of security.
  • If keys are compromised or suspected to be compromised: If you believe a key to be compromised, rotating that key as soon as possible is recommended to reduce the impact window.

Oracle TDE primary key rotation with an HSM key

In this section, you choose a 32-bit hex value to use as a prefix when generating a key, then use that key to update the Oracle database to use the new primary key.

  1. Sign in to the database instance as a user who has the ADMINISTER KEY MANAGEMENT or SYSKM privilege and execute following command:
    ADMINISTER KEY MANAGEMENT SET ENCRYPTION KEY IDENTIFIED BY "<hsm-crypto-user:password>"
    

  2. Decide on a 32-bit hex value pattern to be used. We used 15A5142C9E2D3C2F18FD435814257DFD in this example.
  3. Add the prefix ORACLE.TDE.HSM.MK to the hex pattern.
    ORACLE.TDE.HSM.MK.0615A5142C9E2D3C2F18FD435814257DFD
    

  4. Sign in to CloudHSM and generate a key using the label generated in the previous step.
    key generate-symmetric aes --label 'ORACLE.TDE.HSM.MK.0615A5142C9E2D3C2F18FD435814257DFD' --key-length-bytes 32 —attributes encrypt=true decrypt=true“
    

  5. Share the key with the Oracle hsm-crypto-user in case the original key was generated through another user.
     key share --filter attr.label=""ORACLE.TDE.HSM.MK.0615A5142C9E2D3C2F18FD435814257DFD"" attr.class=secret-key --username hsm_crypto_user --role crypto-user
    

  6. Update the Oracle database to use the new primary TDE key.
    ADMINISTER KEY MANAGEMENT USE KEY '0615A5142C9E2D3C2F18FD435814257DFD' FORCE KEYSTORE IDENTIFIED BY "hsm-crypto-user:password"
    

By following these guidelines, you can enhance the security of your encrypted data, align with regulatory requirements, and maintain robust key management practices.

Conclusion

In this post, we’ve shown you the importance of Transparent Data Encryption (TDE) and the benefits of using an external key manager such as AWS CloudHSM for storing TDE encryption keys. We’ve discussed the benefits of TDE compared to encrypting underlying storage and why using an external key manager is superior to keeping keys on the Oracle wallet on the host. Following these guidelines can help you enhance the security of your encrypted data, align with regulatory requirements, and maintain robust key management practices.

The key takeaways from this post are:

  • TDE offers granular encryption, compliance benefits, and robust key management.
  • External key managers provide enhanced security, centralized management, improved auditability and scalability.
  • Regular rotation of TDE keys is crucial for maintaining security, aligning with regulations, and following recommended practices in key management.

To start securing your Oracle databases with TDE and AWS CloudHSM, visit the AWS Management Console. Follow the steps outlined in this guide to migrate your TDE encryption keystore to AWS CloudHSM and begin rotating your keys regularly to enhance your data security posture. By taking these actions, you can make sure that your sensitive data remains protected, your organization remains aligned with regulations, and you are following the best practices in data encryption and key management.

For more information, see:

If you have feedback about this post, submit comments in the Comments section below.

Bhushan Bhale

Bhushan Bhale

Bhushan is a Senior ISV Solutions Architect at AWS based in Denver, CO with more than 20 years of experience in the technology, telecommunications, and start-up industry. He is a member of the AWS Security TFC with a focus on Data Privacy and Security.

Sudeesh Veettil

Sudeesh Veettil

Sudeesh is a Senior Technical Account Manager at AWS based in the Dallas, TX area, with over 20 years of experience in the technology industry. He specializes in helping customers design, build, and operate secure, resilient, and efficient solutions on AWS.

New Amazon EC2 P6e-GB200 UltraServers accelerated by NVIDIA Grace Blackwell GPUs for the highest AI performance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6e-gb200-ultraservers-powered-by-nvidia-grace-blackwell-gpus-for-the-highest-ai-performance/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6e-GB200 UltraServers, accelerated by NVIDIA GB200 NVL72 to offer the highest GPU performance for AI training and inference. Amazon EC2 UltraServers connect multiple EC2 instances using a dedicated, high-bandwidth, and low-latency accelerator interconnect across these instances.

The NVIDIA Grace Blackwell Superchips connect two high-performance NVIDIA Blackwell tensor core GPUs and an NVIDIA Grace CPU based on Arm architecture using the NVIDIA NVLink-C2C interconnect. Each Grace Blackwell Superchip delivers 10 petaflops of FP8 compute (without sparsity) and up to 372 GB HBM3e memory. With the superchip architecture, GPU and CPU are colocated within one compute module, increasing bandwidth between GPU and CPU significantly compared to current generation EC2 P5en instances.

With EC2 P6e-GB200 UltraServers, you can access up to 72 NVIDIA Blackwell GPUs within one NVLink domain to use 360 petaflops of FP8 compute (without sparsity) and 13.4 TB of total high bandwidth memory (HBM3e). Powered by the AWS Nitro System, P6e-GB200 UltraServers are deployed in EC2 UltraClusters to securely and reliably scale to tens of thousands of GPUs.

EC2 P6e-GB200 UltraServers deliver up to 28.8 Tbps of total Elastic Fabric Adapter (EFAv4) networking. EFA is also coupled with NVIDIA GPUDirect RDMA to enable low-latency GPU-to-GPU communication between servers with operating system bypass.

EC2 P6e-GB200 UltraServers specifications
EC2 P6e-GB200 UltraServers are available in sizes ranging from 36 to 72 GPUs under NVLink. Here are the specs for EC2 P6e-GB200 UltraServers:

UltraServer type GPUs
GPU
memory (GB)
vCPUs Instance memory
(GiB)
Instance storage (TB) Aggregate EFA Network Bandwidth (Gbps) EBS bandwidth (Gbps)
u-p6e-gb200x36 36 6660 1296 8640 202.5 14400 540
u-p6e-gb200x72 72 13320 2592 17280 405 28800 1080

P6e-GB200 UltraServers are ideal for the most compute and memory intensive AI workloads, such as training and inference of frontier models, including mixture of experts models and reasoning models, at the trillion-parameter scale.

You can build agentic and generative AI applications, including question answering, code generation, video and image generation, speech recognition, and more.

P6e-GB200 UltraServers in action
You can use EC2 P6e-GB200 UltraServers in the Dallas Local Zone through EC2 Capacity Blocks for ML. The Dallas Local Zone (us-east-1-dfw-2a) is an extension of the US East (N. Virginia) Region.

To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console. You can select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for u-p6e-gb200x36 or u-p6e-gb200x72 UltraServers.

Once Capacity Block is successfully scheduled, it is charged up front and its price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

To run instances within your purchased Capacity Block, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs. On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.

You can also integrate EC2 P6e-GB200 UltraServers seamlessly with various AWS managed services. For example:

  • Amazon SageMaker Hyperpod provides managed, resilient infrastructure that automatically handles the provisioning and management of P6e-GB200 UltraServers, replacing faulty instances with preconfigured spare capacity within the same NVLink domain to maintain performance.
  • Amazon Elastic Kubernetes Services (Amazon EKS) allows one managed node group to span across multiple P6e-GB200 UltraServers as nodes, automating their provisioning and lifecycle management within Kubernetes clusters. You can use EKS topology-aware routing for P6e-GB200 UltraServers, enabling optimal placement of tightly coupled components of distributed workloads within a single UltraServer’s NVLink-connected instances.
  • Amazon FSx for Lustre file systems provide data access for P6e-GB200 UltraServers at the hundreds of GB/s of throughput and millions of input/output operations per second (IOPS) required for large-scale HPC and AI workloads. For fast access to large datasets, you can use up to 405 TB of local NVMe SSD storage or virtually unlimited cost-effective storage with Amazon Simple Storage Service (Amazon S3).

Now available
Amazon EC2 P6e-GB200 UltraServers are available today in the Dallas Local Zone (us-east-1-dfw-2a) through EC2 Capacity Blocks for ML. For more information, visit the Amazon EC2 pricing page.

Give Amazon EC2 P6e-GB200 UltraServers a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 P6e instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: EC2 C8gn instances, Amazon Nova Canvas virtual try-on, and more (July 7, 2025)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-api-keys-amazon-nova-canvas-virtual-try-on-and-more-july-7-2025/

Every Monday we tell you about the best releases and blogs that caught our attention last week.

Before continuing with this AWS Weekly Roundup, I’d like to share that last month I moved with my family to San Francisco, California, to start a new role as Developer Advocate/SDE, GenAI.

This excites me because I’ll have the opportunity to connect with new communities in the Bay Area while tackling exciting new challenges. If you’re part of a community focused on building generative AI and agentics applications, or know of one, I’d love to connect. Let’s connect!

Last week’s launches
Here are the launches from last week:

  • New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth – Amazon Elastic Compute Cloud (Amazon EC2) C8gn instances are now generally available, powered by AWS Graviton4 processors and 6th generation AWS Nitro Cards. These network-optimized instances deliver up to 600 Gbps network bandwidth. This represents the highest bandwidth among EC2 network-optimized instances, with up to 192 vCPUs and 384 GiB memory. They provide 30% higher compute performance than C7gn instances and are ideal for network-intensive workloads like virtual appliances, data analytics, and cluster computing jobs.
  • Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables – Amazon DynamoDB global tables now supports multi-Region strong consistency (MRSC) for applications requiring zero Recovery Point Objective (RPO). This capability ensures applications can read the latest data from any Region during outages, addressing critical needs in payment processing and financial services. MRSC requires three AWS Regions configured as either three full replicas or two replicas plus a witness, providing the highest level of application resilience for mission-critical workloads.
  • Amazon Nova Canvas update: Virtual try-on and style options now available – Amazon Nova Canvas introduces virtual try-on capabilities that help you visualize how clothing looks on a person by combining two images, plus eight new pre-trained style options (3D animation, design sketch, vector illustration, graphic novel, etc.) for generating images with improved artistic consistency. Available in three AWS Regions, these features enhance AI-powered image generation capabilities for retailers and content creators seeking realistic product visualizations.
  • Amazon Q in Connect now supports 7 languages for proactive recommendations – Amazon Q in Connect, a generative AI-powered assistant for customer service, now provides proactive recommendations in seven languages: English, Spanish, French, Portuguese, Mandarin, Japanese, and Korean. The AI-powered customer service assistant detects customer intent during voice and chat interactions to help agents resolve issues quickly and accurately.
  • Amazon Aurora MySQL and Amazon RDS for MySQL integration with Amazon SageMaker is now available – This integration provides near real-time data availability for analytics. It automatically extracts MySQL data into lakehouses with Apache Iceberg compatibility. You can then access this data seamlessly through various analytics engines and machine learning tools.
  • Amazon Aurora DSQL is now available in additional AWS Regions – Amazon Aurora DSQL expands to Asia Pacific (Seoul) and now supports multi-Region clusters across Asia Pacific and European regions. This serverless, distributed SQL database offers unlimited scalability, highest availability, and zero infrastructure management with AWS Free Tier access.

Other AWS blog posts

  • Optimize RAG in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service – Learn how to optimize Retrieval Augmented Generation (RAG) in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service. This comprehensive guide demonstrates implementing RAG workflows with LangChain, covers OpenSearch optimization strategies, provides setup instructions, and explains benefits of combining these AWS services for scalable, cost-effective generative AI applications.v
  • Agentic GenAI App Using Bedrock, MCP servers on EKS – This post shows how to build a scalable AI chat application using Amazon Bedrock, Strands Agent, and Model Context Protocol (MCP) servers deployed on Amazon Elastic Kubernetes Service (Amazon EKS). The architecture combines agentic workflows with containerized microservices for intelligent, auto-scaling conversations with multiple foundation models.
  • Enforce table level access control on data lake tables using AWS Glue 5.0 with AWS Lake Formation – AWS Glue 5.0 introduces Full-Table Access (FTA) control for Apache Spark with AWS Lake Formation, providing table-level security without fine-grained access overhead. This feature supports native Spark SQL/DataFrames for Lake Formation tables. It enables read/write operations on Iceberg and Hive tables with improved performance and lower costs.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. Early-career professionals can apply for the All Builders Welcome Grant program, designed to remove financial barriers and create diverse pathways into cloud technology. Applications are now open and close on July 15, 2025.
  • AWS NY Summit – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • Join AWS Gen AI Lofts – Experience AWS Gen AI Lofts across San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, Tel Aviv, and additional locations – hands-on workshops, expert guidance, investor networking, and collaborative spaces designed to accelerate your generative AI startup journey.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Eli

New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: New AWS Heroes, Amazon Q Developer, EC2 GPU price reduction, and more (June 9, 2025)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-new-aws-heroes-amazon-q-developer-ec2-gpu-price-reduction-and-more-june-9-2025/

The AWS Heroes program recognizes a vibrant, worldwide group of AWS experts whose enthusiasm for knowledge-sharing has a real impact within the community. Heroes go above and beyond to share knowledge in a variety of ways in developer community. We introduce our newest AWS Heroes in the second quarter of 2025.

To find and connect with more AWS Heroes near you, visit the categories in which they specialize Community Heroes, Container Heroes, Data Heroes, DevTools Heroes, Machine Learning Heroes, Security Heroes, and Serverless Heroes.

Last week’s launches
In addition to the inspiring celebrations, here are some AWS launches that caught my attention.

For a full list of AWS announcements, be sure to keep an eye on What’s New at AWS.

Other AWS news
Here are some additional projects, blog posts that you might find interesting:

  • Up to 45 percent price reduction for Amazon EC2 NVIDIA GPU-accelerated instances – AWS is reducing the price of NVIDIA GPU-accelerated Amazon EC2 instances (P4d, P4de, P5, and P5en) by up to 45 percent for On-Demand and Savings Plan usage. We are also making the very new P6-B200 instances available through Savings Plans to support large-scale deployments.
  • Introducing public AWS API models – AWS now provides daily updates of Smithy API models on GitHub, enabling developers to build custom SDK clients, understand AWS API behaviors, and create developer tools for better AWS service integration.
  • The AWS Asia Pacific (Taipei) Region is now open – The new Region provides customers with data residency requirements to securely store data in Taiwan while providing even lower latency. Customers across industries can benefit from the secure, scalable, and reliable cloud infrastructure to drive digital transformation and innovation.
  • Amazon EC2 has simplified the AMI cleanup workflow – Amazon EC2 now supports automatically deleting underlying Amazon Elastic Block Store (Amazon EBS) snapshots when deregistering Amazon Machine Images (AMIs).
  • The Lab where AWS designs custom chips – Visit Annapurna Labs in Austin, Texas—a combination of offices, workshops, and even a mini data center—where Amazon Web Services (AWS) engineers are designing the future of computing.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events.

  • Join re:Inforce from anywhere – If you aren’t able to make it to Philadelphia (June 16–18), tune in remotely. Get free access to the re:Inforce keynote and innovation talks live as they happen.
  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Shanghai (June 19 – 20), Milano (June 18), Mumbai (June 19) and Japan (June 25 – 26).
  • AWS re:Invent – Mark your calendars for AWS re:Invent (December 1 – 5) in Las Vegas. Registration is now open
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Mexico (June 14), Nairobi, Kenya (June 14) and Colombia (June 28)

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Betty

Announcing up to 45% price reduction for Amazon EC2 NVIDIA GPU-accelerated instances

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-up-to-45-price-reduction-for-amazon-ec2-nvidia-gpu-accelerated-instances/

Customers across industries are harnessing the power of generative AI on AWS to boost employee productivity, deliver exceptional customer experiences, and streamline business processes. However, the growth in demand for GPU capacity has outpaced industry-wide supply, making GPUs a scarce resource and increasing the cost of securing them.

As Amazon Web Services (AWS) grows, we work hard to lower our costs so that we can pass those savings back to our customers. Regular price reductions on AWS services have been a standard way for AWS to pass on the economic efficiencies gained from our scale back to our customers.

Today, we’re announcing up to 45 percent price reduction for Amazon Elastic Compute Cloud (Amazon EC2) NVIDIA GPU-accelerated instances: P4 (P4d and P4de) and P5 (P5 and P5en) instance types. This price reduction to On-Demand and Savings Plan pricing applies to all Regions where these instances are available. The pricing reduction applies to On-Demand purchases beginning June 1 and to Savings Plan purchases effective after June 4.

Here is a table of price reductions percentage (%) from May 31, 2025 baseline prices by instance types and pricing plans:

Instance type NVIDIA GPUs On-Demand EC2 Instance Savings Plans Compute Savings Plans
1 year 3 years 1 year 3 years
P4d A100 33% 31% 25% 31% –
P4de A100 33% 31% 25% 31% –
P5 H100 44% – 45% 44% 25%
P5en H200 25% – 26% 25% –

Savings Plans are a flexible pricing model that offer low prices on compute usage, in exchange for a commitment to a consistent amount of usage (measured in $/hour) for a 1- or 3- year term. We offers two types of Savings Plans:

  • EC2 Instance Savings Plans provide the lowest prices, offering savings in exchange for commitment to usage of individual instance families in a Region (for example, P5 usage in the US (N. Virginia) Region).
  • Compute Savings Plans provide the most flexibility and help to reduce your costs regardless of instance family, size, Availability Zones, and Regions (for example, from P4d to P5en instances, shift a workload between US Regions).

To provide increased accessibility to reduced pricing, we are making at-scale On-Demand capacity available for:

  • P4d instances in the Asia Pacific (Seoul), Asia Pacific (Sydney), Canada (Central), and Europe (London) Regions
  • P4de instances in the US East (N. Virginia) Region
  • P5 instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), Asia Pacific (Jakarta), and South America (São Paulo) Regions
  • P5en instances in the Asia Pacific (Mumbai), Asia Pacific (Tokyo), and Asia Pacific (Jakarta) Regions

We are also now delivering Amazon EC2 P6-B200 instances through Savings Plan to support large scale deployments, which became available on May 15, 2025 at launch only through EC2 Capacity Blocks for ML. EC2 P6-B200 instances, powered by NVIDIA Blackwell GPUs, accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing.

These pricing updates reflect the AWS commitment to making advanced GPU computing more accessible while passing cost savings directly to customers.

Give Amazon EC2 NVIDIA GPU-accelerated instances a try in the Amazon EC2 console. To learn more about these pricing updates, visit Amazon EC2 Pricing page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Optimizing ODCR usage through AI-powered capacity insights

Post Syndicated from Ankush Goyal original https://aws.amazon.com/blogs/compute/optimizing-odcr-usage-through-ai-powered-capacity-insights/

Efficient resource management is crucial for organizations seeking to optimize cloud costs while making sure of seamless access to compute capacity. Amazon Elastic Compute Cloud (Amazon EC2) On-Demand Capacity Reservations (ODCRs) provide the flexibility to reserve compute capacity within a specific Availability Zone (AZ) for any duration. This makes sure that critical workloads always have the necessary resources available, minimizing the risk of capacity shortages.

However, managing ODCRs across multiple teams and accounts presents several challenges:

  • Limited visibility across teams: In large organizations, tracking ODCR usage across teams and business units can be difficult, often leading to underused or duplicate reservations.
  • Complexity in optimization: Without clear insights, adjusting, releasing, or modifying reservations to align with changing workloads becomes a cumbersome process.
  • Cost management challenges: Unused or oversized ODCRs contribute to unnecessary expenses, making it essential to continuously monitor and optimize usage.

In this post, we demonstrate how Amazon Bedrock Agents can help organizations gain actionable insights into ODCR usage across their Amazon Web Services (AWS) environment. Unlike traditional approaches that rely on predefined patterns or manual tracking, this solution dynamically retrieves the latest ODCR usage data and provides intelligent, query-based recommendations to fulfill the capacity needs. This solution is serverless and pay-per-use and incurs minimal operational cost.

This approach allows IT leaders, cloud architects, and finance teams to optimize reservations, control costs, and enhance overall resource management—without the complexity of traditional analysis methods.

Solution overview

This solution addresses two specific use cases:

  1. The team must create a new ODCR to accommodate an upcoming project.
  2. The team needs to expand the capacity of their existing ODCR.

The system consists of three essential components:

  • ODCRSupervisorAgent: Functions as the main coordinator, handling user inquiries and managing requests to specialized subordinate agents.
  • CapacityPlanningAgent: Reviews existing ODCRs throughout the organization, recommending SPLIT and MOVE operations to optimize capacity allocation for new projects.
  • AugmentationAgent: Identifies opportunities to increase existing ODCR capacity by recommending MOVE operations from other organizational ODCRs.

The following figure shows the high-level architecture for this solution.

The system architecture uses AWS services for comprehensive ODCR management, as shown in the following figure. The platform combines Amazon Cognito for authentication, AWS Amplify for front-end delivery, and AWS Lambda for serverless computing. AWS Resource Explorer enables efficient discovery and tracking of ODCRs across AWS Regions, while Lambda functions periodically query Resource Explorer to retrieve detailed ODCR information and usage metrics. AWS Identity and Access Management (IAM) plays a crucial role in securing the system, managing fine-grained access controls and permissions across all components. Amazon Bedrock Agents and its multi-agent capabilities generate intelligent recommendations through coordinated agent interactions, allowing organizations to optimize ODCR usage and implement data-driven capacity planning strategies.

How the solution functions

At the heart of this system is an Amazon Bedrock Agent powered by Action Groups, which map user queries to backend tasks using Lambda. These Lambda functions act as the system’s intelligence layer: fetching, filtering, and formatting ODCR data for the agent to reason over. The following three Lambda functions are deployed as part of the AWS CloudFormation template:

get_az_mapping_info Lamba function: This Lambda function takes an AWS account ID and Region as input. It returns a mapping of AZ names to their corresponding AZ IDs for that account and AWS Region. This helps the Capacity Planning Agent align AZs across accounts.

find_eligiable_odcrs Lambda function: This Lambda function supports the Capacity Planning Agent by identifying suitable ODCRs that meet the specified instance type and AZ. It uses Resource Explorer to search for ODCRs across the organization. Then, the function assumes cross-account roles to access ODCRs in different AWS accounts to gather detailed information. After retrieving the necessary data, it filters the ODCRs based on instance type, tenancy, and AZ. Finally, it returns a formatted list of eligible ODCRs, which are sourced from either the specified account or an alternative account with adequate capacity.

find_eligible_odcrs_for_move Lambda function: This Lambda function assists the Augmentation Agent by finding all capacity reservations within the same account as the specified ODCR. It uses Resource Explorer to discover ODCRs and, when necessary, assumes cross-account roles to gather ODCR information. The function filters ODCRs based on matching instance type, tenancy, and AZ, then returns a formatted list of eligible ODCRs that can provide more capacity through MOVE operations.

Each Lambda function receives structured inputs from the Amazon Bedrock Agent, executes its designated task, and returns structured responses. Then, these responses are used by the agent to generate intelligent, actionable answers to user queries.

Together, these Lambda functions extend the capabilities of the Amazon Bedrock Agent by integrating with external data sources and automating complex ODCR management logic—allowing the system to deliver accurate, dynamic recommendations.

Prerequisites

You must have the following in place to implement the solution in this post:

Deploy solution resources using CloudFormation

This solution is designed to be deployed in a single Region. If deploying outside us-east-1, then you must modify the CloudFormation parameters to reference the correct FM version and adjust for Regional availability, such as any necessary cross-Region inference profile configurations.

  • Deploy the Cross Account IAM Role template: To access ODCR data across your Organization, deploy a CloudFormation StackSet from your payer account. During deployment, you must provide the account number where you plan to deploy the ODCR solution. This is the same account number that you used as delegate account for Resource Explorer under the prerequisites. This account number is added to the trust policy of the IAM role, allowing the solution in that account to assume the role created by the StackSet. The deployment automatically provisions a standardized IAM role with the necessary permissions (for example ec2:DescribeCapacityReservations and ec2:DescribeAvailabilityZones) in each target account.
  • Deploy the ODCR Solution template: Deploy the provided template in the delegated administrator account that you chose for Resource Explorer. This sets up the core components of the solution and integrates with your payer account for organization-wide ODCR insights.

Resources deployed by the CloudFormation template

After you have deployed the CloudFormation template, the following AWS resources are created in your account.

Cross Account IAM Role template

  • IAM resource
    • CrossAccountODCRAccessRole

ODCR Solution template

  • Amazon Cognito resources:
    • User Pool: ODCRAgentUserPool
    • App Client: ODCRAgentApp
    • Identity Pool: odcr-identity-pool
    • Groups: ODCRAdmins
    • User: ODCR User
  • IAM resources:
    • IAM roles:
      • GetAZMappingFunctionRole
      • LambdaODCRAccessRole
      • BedrockAgentExecutionRole
      • ODCRSupervisorAgentExecutionRole
      • CognitoAuthRole
  • Lambda functions:
    • get_az_mapping_info
    • find_eligible_odcrs
    • find_eligible_odcrs_for_move
  • Amazon Bedrock Agents
    • ODCRSupervisorAgent
    • CapacityPlanningAgent with action groups:
      • get_az_mapping_info
      • find_eligible_odcrs
    • AugmentationAgent with action group:
      • find_eligible_odcrs_for_move

After you deploy the final CloudFormation template, copy the following from the Outputs tab on the CloudFormation console to use during the configuration of your application after it’s deployed in Amplify:

  • AWSRegion
  • BedrockAgentAliasId
  • BedrockAgentId
  • BedrockAgentName
  • IdentityPoolId
  • UserPoolClientId
  • UserPoolId

The following screenshot shows you what the Outputs tab looks like.

Deploy the Amplify application for front-end

You need to manually deploy the Amplify application using the front-end code found on GitHub. Complete the following steps, as shown in the following figure:

  1. Download the front-end code AWS-Amplify-Frontend.zip from GitHub.
  2. Use the .zip file to manually deploy the application in Amplify.
  3. Return to the Amplify page and use the domain that it automatically generated to access the application.

After completing these steps, your environment is ready to analyze ODCR usage and receive recommendations powered by Amazon Bedrock Agents.

Solution walkthrough

After deploying the application in Amplify, return to the Amplify console. Use the auto-generated domain URL shown there to access the front-end. Upon accessing the application URL, you’re prompted to provide information related to Amazon Cognito and Amazon Bedrock Agents. This information is necessary to securely authenticate users and allow the front end to interact with the Amazon Bedrock Agent. It enables the application to manage user sessions and make authorized API calls to AWS services on behalf of the user.

You can enter information with the values that you collected from the CloudFormation stack outputs, as shown in the following screenshot:

A temporary password was automatically generated during deployment and sent to the email address provided when launching the CloudFormation template. At first sign-in, you’re prompted to reset your password.When you’re signed in, you can begin interacting with the application to analyze and manage your ODCR usage. The interface supports natural language queries to streamline capacity planning. The following are some example questions that you can ask:

  • I require [X units] of capacity for the [INSTANCE TYPE] instance type in Availability Zone [AZ ID], within account [ACCOUNT NUMBER]. Could you please advise if there are any existing On-Demand Capacity Reservations (ODCRs) that can fulfill this requirement? Additionally, what operations would be necessary to utilize the available capacity?

  • I have a requirement to add [X additional units] of capacity to an existing On-Demand Capacity Reservation with ID [cr-0012abcd123456789]. Could you please advise on the steps or operations required to fulfill this request?

Cleaning up

If you decide to discontinue using this solution, then you can follow these steps to remove it, its associated resources deployed using CloudFormation, and the Amplify deployment:

  1. Delete the CloudFormation StackSet:
    1. On the CloudFormation console, choose StackSets in the navigation pane.
    2. Locate your StackSet for the Cross-Account IAM Role (you assigned a name to it).
    3. Choose Delete stacks from StackSet to remove all stack instances.
    4. After all instances are deleted, choose StackSet.
    5. Choose Delete StackSet from the Actions menu.
  2. Delete the CloudFormation stack:
    1. On the CloudFormation console, choose Stacks in the navigation pane.
    2. Locate the stack you created during the deployment process (you assigned a name to it).
    3. Choose the stack and choose Delete.
  3. Delete the Amplify application and its resources. For instructions, refer to Clean Up Resources.

Conclusion

In this post, we demonstrated how to use Amazon Bedrock Agents and AWS services to build an intelligent ODCR management solution. Combining AWS Resource Explorer for organization-wide visibility, Amazon Bedrock Agents for intelligent recommendations, and a secure front-end powered by AWS Amplify, organizations can now make data-driven decisions about their capacity reservations. This solution helps teams optimize ODCR usage, reduce costs, and efficiently manage compute capacity across their AWS Organization. The artificial intelligence (AI)-powered approach eliminates manual tracking and analysis, allowing teams to focus on strategic capacity planning rather than operational overhead.

Get started today by deploying this solution in your AWS environment, and unlock the power of AI-driven capacity insights for more efficient ODCR management.

PackScan: Building real-time sort center analytics with AWS Services

Post Syndicated from Sairam Vangapally original https://aws.amazon.com/blogs/big-data/packscan-building-real-time-sort-center-analytics-with-aws-services/

Amazon manages a complex logistics network with multiple touch points, from fulfillment centers to sort centers to final customer delivery. Among these, sort centers play a crucial role in the middle mile, providing faster and more efficient package movement. Within Amazon’s Middle Mile operations, high-volume sort centers process millions of packages daily, making immediate access to operational data essential for optimizing efficiency and decision-making. Real-time visibility into key metrics—such as package movements, container statuses, and associate productivity—is critical for smooth logistics operations. To address the need for real-time operational planning, the Amazon Middle Mile team developed PackScan, a cloud-based platform designed to provide instant insights across the network. By significantly reducing data latency, PackScan enables proactive decision-making, so teams can monitor inbound package flows, optimize outbound shipments based on live data, track associate productivity, identify bottlenecks, and enhance overall operational efficiency—all in real time.

In this post, we explore how PackScan uses Amazon cloud-based services to drive real-time visibility, improve logistics efficiency, and support the seamless movement of packages across Amazon’s Middle Mile network.

Prerequisites

This post assumes a foundational understanding of the following services and concepts:

Although hands-on experience is not required, a conceptual understanding of these services will help in understanding the architecture, design patterns, and components discussed throughout the article.

Business challenges

Amazon’s sort centers handle over 15 million packages daily across more than 120 facilities in North America. Given this scale, even minor delays in operational insights can lead to inefficiencies, increased costs, and escalations. Traditionally, data latencies of up to an hour have restricted the ability to make proactive decisions, directly affecting productivity, resource allocation, and responsiveness—especially during peak periods like holiday seasons and big deal days.

Without immediate visibility into package movements, container statuses, and associate performance, operational teams face challenges in identifying and resolving bottlenecks in real time. The lack of timely insights can disrupt the flow of packages, leading to shipment delays, reduced throughput, and suboptimal facility performance. Addressing these inefficiencies required a solution capable of delivering real-time, high-fidelity data to support rapid decision-making.

To bridge this gap, Amazon’s Middle Mile organization needed a scalable platform that could enhance visibility, minimize latency, and provide up-to-the-minute insights into logistics operations. PackScan was designed to meet these demands, giving teams access to the real-time data necessary to optimize workflows, mitigate bottlenecks, and improve overall efficiency.

Data flow

In 2024, PackScan was deployed across 80 sort centers in the USA, enabling real-time package analytics. The solution powers Grafana dashboards, which refresh every 10 seconds by fetching live package data from OpenSearch Service. With this near real-time visibility, operations teams can monitor package movement and sorting efficiency across sort centers. The following diagram outlines how package scan data is ingested, processed, and made actionable.

Each sort center is equipped with hardware at inbound stations where packages arrive from trailers. Integrated barcode scanners automatically scan each package as it enters the sorting process. Every scan generates an SNS event, capturing key attributes such as the package ID, dimensions, the associate who performed the scan, and the timestamp and location of the scan.

After they’re generated, these SNS events are ingested into Data Firehose through a Lambda function, where the data undergoes real-time enrichment. During this process, additional attributes are appended, including the business logic rules. The enriched data is then streamed into OpenSearch Service, where events are indexed to enable fast and efficient querying. With the indexed package scan events available in OpenSearch Service, real-time analytics and monitoring become possible. The Grafana dashboards query this data every 10 seconds, providing operational insights into package inflow metrics and associate performance.

Solution overview

PackScan was implemented using a structured and scalable approach, using AWS cloud-based services to enable high-frequency data ingestion, real-time processing, and actionable insights. The architecture is designed to minimize latency while providing reliability, scalability, and operational efficiency. The solution is built around a serverless, event-driven architecture that dynamically scales based on data ingestion volumes. The architecture—illustrated in the following figure—enabled us to build a real-time data solution, utilizing the advantages of various AWS services to provide low-latency analytics, high scalability, and real-time operational insights across Amazon’s sort centers.

The following are the key components and features of the solution:

  • Real-time data processing – Lambda functions serve as the processing backbone of the system, handling 500,000 scan events per second. Each incoming event is processed by applying data transformations, enrichment, and validation before passing it downstream.
  • High-frequency data ingestion and streaming – Data Firehose is the primary ingestion pipeline, handling millions of scan events daily from thousands of barcode scanners across multiple sort centers. The Firehose streams handle incoming data of 12,000 PUT requests per second, maintaining smooth ingestion and low-latency streaming. Data retention policies are set to buffer and forward enriched events every 60 seconds or upon reaching 5 MB batch size, optimizing storage and processing efficiency.
  • Optimized querying and operational insights – OpenSearch Service is used to index and store the processed scan events, providing real-time querying and anomaly detection. The OpenSearch cluster consists of 12 data nodes (r5.4xlarge.search) and 3 primary nodes (r5.large.search), processing up to 10 GB of data per day with a rolling index strategy, where indexes are rotated every 24 hours to maintain query performance. The system supports concurrent queries per second, enabling logistics teams to perform rapid lookups and gain instant visibility into package movements.
  • Live visualization and dashboarding – Grafana, hosted on an m5.12xlarge EC2 instance, provides real-time visualization of key logistics metrics. The dashboards refresh every 10 seconds, querying OpenSearch and displaying up-to-the-minute package analytics. The setup includes multiple preconfigured dashboards, monitoring package flow at different inbound stations, and workforce efficiency. These dashboards support concurrent users, enabling supervisors and associates to track and optimize operations proactively. The following screenshot shows one of the real-time dashboards, with details of package flow by different routes within sort centers.

The entire PackScan architecture is designed for automatic scaling, adjusting dynamically based on data ingestion volume to maintain efficiency during peak and off-peak operations. This approach provides cost-effective resource utilization while maintaining high availability and performance.

Business outcomes

The implementation of PackScan has led to measurable improvements in operational efficiency, workforce productivity, and real-time decision-making across Amazon’s sort centers. By reducing data latency and enabling real-time insights, PackScan has transformed logistics operations in meaningful ways:

  • Widespread deployment – PackScan was deployed across 80 sort centers, supporting approximately 1,000 display monitors that provide real-time operational insights.
  • Significant reduction in data latency – Data latency dropped from approximately 1 hour to less than 1 minute, allowing for real-time operational responsiveness and minimizing workflow disruptions.
  • Proactive operational management – With dynamic workload balancing and instant bottleneck identification, supervisors can now address issues as they arise, leading to smoother operations and fewer escalations.
  • Boost in workforce productivity – The real-time performance feedback has enhanced associate engagement, resulting in a 25% increase in throughput per hour and 12% reduction in labor hours.

Overall, PackScan has redefined real-time logistics visibility within Amazon’s Middle Mile operations, empowering operational teams with actionable insights, enhanced workforce efficiency, and a data-driven approach to package movement and sort center performance.

Lessons learned and best practices

The deployment and scaling of PackScan provided valuable insights into optimizing real-time logistics visibility. Several key lessons and best practices emerged from this implementation:

  • Cloud architecture drives efficiency – Adopting Amazon technologies provides seamless scalability, reduced operational overhead, and lower infrastructure costs, while maintaining high reliability. The following table shows an approximate breakdown of monthly service costs observed in production. This is an estimation based on current pricing; we recommend checking the respective AWS service pricing pages to generate the most up-to-date quote. This architecture demonstrates that with combination of provisioned and serverless design, production-ready solutions can be built and scaled at a fraction of the cost of traditional infrastructure.
AWS Service Description Estimated Monthly Cost
Amazon EC2 Three EC2 instances of type m5.12xlarge hosting Grafana $1,700
AWS Lambda Streams SNS events to Data Firehose $4,000
Amazon Data Firehose Real-time data delivery with 12,000 records streaming to OpenSearch Service $1,500
Amazon OpenSearch Service Indexing and querying package scan events $28,000
  • Real-time visibility is a game changer – Immediate access to operational data enhances agility, enabling teams to make timely, data-driven decisions that prevent bottlenecks and improve throughput.
  • Continuous monitoring enhances decision-making – Operational dashboards should evolve with business needs. Regular monitoring and updates provide accuracy, usability, and relevance in driving informed decision-making.

By applying these best practices, PackScan has set a foundation for scalable, real-time logistics management, making sure that Amazon’s Middle Mile operations remain proactive, efficient, and highly responsive to changing business demands.

Conclusion

PackScan has successfully transformed real-time operational visibility within Amazon’s sort centers, addressing critical challenges in data latency, workforce productivity, and logistics efficiency. By using AWS services, particularly Data Firehose for real-time data delivery and OpenSearch Service for analytics, PackScan has enabled proactive decision-making, streamlined operations, and enhanced throughput in high-volume sort environments. Looking ahead, future enhancements will focus on further elevating operational intelligence and scalability, including:

  • Integrating predictive analytics to anticipate workflow bottlenecks and optimize resource allocation
  • Scaling the solution across additional operational scenarios, providing greater resilience and adaptability to dynamic logistics environments

With these advancements, PackScan will continue to drive operational excellence, cost-efficiency, and real-time decision-making capabilities, reinforcing Amazon’s commitment to innovation in logistics and supply chain management.

For those interested in implementing similar solutions, we recommend exploring AWS Serverless Architecture Patterns and the AWS Architecture Blog for additional insights and best practices in building scalable, real-time analytics solutions.


About the authors

Sairam Vangapally is a Data Engineer at Amazon with extensive experience architecting real-time, large-scale data platforms that power critical logistics operations across North America. He has led the design and deployment of end-to-end data pipelines, enabling high-throughput ingestion, transformation, and analytics at scale. He is passionate about building resilient data infrastructure and driving cross-functional collaboration to deliver solutions that accelerate operational insights and business impact.

Nitin Goyal serves as a Data Engineering Manager in Amazon’s Sort Center organization, where he leads initiatives to optimize operational efficiency across North American facilities. With over nine years of tenure at Amazon spanning multiple teams, he specializes in architecting high-performance data systems, with particular emphasis on real-time streaming pipelines, artificial intelligence, and low-latency solutions. His expertise drives the development of sophisticated operational workflows that enhance sort center productivity and effectiveness.

How to secure your instances with multi-factor authentication

Post Syndicated from Sangavi P original https://aws.amazon.com/blogs/compute/how-to-secure-your-instances-with-multi-factor-authentication/

At AWS, security is our top priority. We strongly recommend implementing comprehensive security controls across all application layers to ensure defense-in-depth. This multi-layered approach helps protect your workloads, data, and infrastructure from potential threats. In this post, we walk through implementing an additional layer of authentication security for your Amazon Linux 2023 (AL2023) Amazon Elastic Compute Cloud (Amazon EC2) instances by using two-factor authentication while connecting to the instance through Secure Shell (SSH).

SSH Access Security Fundamentals

The most common tool to connect to Linux servers is SSH. When an EC2 instance is launched, you are prompted to either create a new key pair or use an existing key pair to connect to the EC2 instance using SSH. The key pair is a combination of a private and public key, where the public key is stored within the instance in the ~/.ssh/authorized_keys file, while the private key is stored in the user’s machine. A compromised local machine containing SSH private keys poses a significant security risk. An attacker who obtains both the private key and the corresponding EC2 instance username could gain unauthorized SSH access to your instance with the same permissions as the compromised user account. To prevent anyone with the private keypair from accessing the instance you should implement two-factor auth through multi-factor authentication (MFA).

Configuring security groups to allow unrestricted SSH access (0.0.0.0/0) to EC2 instances’ public IP addresses creates a significant security vulnerability. This practice exposes your instances to potential brute force attacks and unauthorized access attempts from anywhere on the internet. To overcome this, we either recommend a user restricts the access to only “My IP” in the security group, or to have a bastion host or a jump box in front of your instances and access your instances through your bastion host. Implementing MFA on top of this would tighten the security while accessing the instances through SSH.

The following figure shows a common architecture anti-pattern:

The following figure shows the recommended architectures:

Prerequisites

Before proceeding, install the Google Authenticator app on your mobile device – you’ll need it to generate one-time passwords (OTPs) for Multi-Factor Authentication (MFA) on your Amazon Linux 2023 instances.

Configuration Steps

Install Google Authenticator in the EC2 instance

Login to the instance and install Google Authenticator and its dependencies.

$ sudo dnf install google-authenticator qrencode -y

Configuring Google Authenticator

After installing the package, the application has to be initialized to generate a key for the user that you are logged in as (for example ec2-user) to add the authentication to that user account. Execute the following command to initialize the application.

google-authenticator

You are asked if the authentication tokens used should be time-based. In this example, you use time-based tokens.

Do you want authentication tokens to be time-based (y/n) y

This generates a QR code that you should scan using your Google Authenticator app. Then, enter the verification code from the application in the terminal after scanning, or manually enter the account name, which is any name, to recognize the instance and the secret key displayed in the terminal in the application to register your instance. After confirming the code, the system will generate emergency scratch codes. Store these codes securely – they serve as backup authentication methods if you lose access to your Google Authenticator app or mobile device. Each scratch code can be used only once.

After registering the instance details in the mobile application through QR code or manual operation, in the SSH terminal you are asked if the google_authenticator file should be updated for user ec2-user. Typing y saves the secret key, scratch codes, and the other configuration options that you select later on in the file. Run the initialization app and go through the same procedure for each user account to enable MFA on each account.

Do you want me to update your "/home/ec2-user/.google_authenticator" file (y/n) y

Choose y for the following question to refuse multiple uses of the same authentication token to enhance security and prevent a man-in-the-middle attack.

Do you want to disallow multiple uses of the same authentication token? 
This restricts you to one login about every 30s, but it increases your chances 
to notice or even prevent man-in-the-middle attacks (y/n) y

Choose n for the following question to have three valid codes in a 1:30-minute window unless you are facing issues.

By default, a new token is generated every 30 seconds by the mobile app.
In order to compensate for possible time-skew between the client and the server, 
we allow an extra token before and after the current time. 
This allows for a time skew of up to 30 seconds between authentication server and client. 
If you experience problems with poor time synchronization, 
you can increase the window from its default size of 3 permitted codes 
(one previous code, the current code, the next code) to 17 permitted codes 
(the 8 previous codes, the current code, and the 8 next codes). 
This will permit for a time skew of up to 4 minutes between client and server. 
Do you want to do so? (y/n) n

Choose y for the following question to enable rate-limiting to protect against brute-force logic attempts.

If the computer that you are logging into isn't hardened against brute-force 
login attempts, you can enable rate-limiting for the authentication module.
By default, this limits attackers to no more than 3 login attempts every 30s. 
Do you want to enable rate-limiting (y/n) y

Configure SSH to use the Google Pluggable Authentication module

By default PAM is not configured to use MFA for SSH connections. Now that you have the MFA module configured and running, you must modify the PAM configurations to use MFA authentication.

sudo vi /etc/pam.d/sshd

There are two options for configuration to choose from based on your requirement.

Option 1: Configuring MFA for all users in the instance

Add the following to the bottom of the file to use Google Authenticator to enforce MFA for SSH connections. When this option is enabled, the system will prompt all users for MFA during SSH connections, regardless of whether MFA has been configured for their individual accounts. This applies to every user attempting to access the instance, which may disrupt access for users without MFA configuration.

Important: Before implementing this setting, ensure all users who need instance access have properly configured MFA to prevent potential lockouts.

auth required pam_google_authenticator.so 
auth required pam_permit.so

Option 2: Configuring for specific users without affecting others

If there are other service accounts or users within the instance that should be able to log in without MFA, then add nullok at the end of the following statement. This means that users who don’t run Google Authenticator initialization won’t be asked for a second authentication.

auth required pam_google_authenticator.so nullok 
auth required pam_permit.so

Comment out the password requirement, as SSH key pairs provide stronger security than password-based authentication. In this configuration, users will need both an SSH key and a verification code from Google Authenticator to establish an SSH connection – eliminating password prompts while maintaining robust security through two-factor authentication. Note that if you leave password authentication enabled (by not commenting out this line), users will be required to provide three factors: their SSH key, password and MFA code to access the instance.

#auth       substack     password-auth

Save the file. You must change the SSH configuration to make it prompt for a second authentication. Run the following command to make changes in the configuration file.

sudo vi /etc/ssh/sshd_config.d/50-redhat.conf 

Then, change ChallengeResponseAuthentication no to ChallengeResponseAuthentication yes.

Lastly, you must let SSH know that it should use key pair along with interactive authentication for the MFA module to login. At the bottom of the file, add the following:

AuthenticationMethods publickey,keyboard-interactive

Save the file. Restart the SSH service running in the instance to let the changes take effect. Restarting the SSH service (the SSH daemon) stops the main sshd process and starts a new one, but it doesn’t disconnect existing SSH sessions.

sudo /etc/init.d/sshd restart

To test the solution, open a new terminal window and SSH into the instance, and you are asked for a verification code. Keep your session in the original terminal window open while you SSH from your new window.

Type the code that’s generated on your Google Authenticator app and you are logged in to your instance.

Using MFA allows to add a further layer of security to Amazon Linux 2023 EC2 instances while logging in.

Cleanup

To avoid incurring charges, please stop or terminate the launched Amazon EC2 instance if not in use.

Conclusion

In this post, you learned how to enhance your Amazon Linux 2023 EC2 instance security by implementing multi-factor authentication (MFA) with Google Authenticator. This setup requires users to provide both their SSH key pair and a time-based one-time password from their application when connecting to instances, adding an essential extra layer of protection.

New Amazon EC2 P6-B200 instances powered by NVIDIA Blackwell GPUs to accelerate AI innovations

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6-b200-instances-powered-by-nvidia-blackwell-gpus-to-accelerate-ai-innovations/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6-B200 instances powered by NVIDIA B200 to address customer needs for high performance and scalability in artificial intelligence (AI), machine learning (ML), and high performance computing (HPC) applications.

Amazon EC2 P6-B200 instances accelerate a broad range of GPU-enabled workloads but are especially well-suited for large-scale distributed AI training and inferencing for foundation models (FMs) with reinforcement learning (RL) and distillation, multimodal training and inference, and HPC applications such as climate modeling, drug discovery, seismic analysis, and insurance risk modeling.

When combined with Elastic Fabric Adapter (EFAv4) networking, hyperscale clustering by EC2 UltraClusters, and advanced virtualization and security capabilities by AWS Nitro System, you can train and serve FMs with increased speed, scale, and security. These instances also deliver up to two times the performance for AI training (time to train) and inference (tokens/sec) compared to EC2 P5en instances.

You can accelerate time-to-market for training FMs and deliver faster inference throughput, which lowers inference cost and helps increase adoption of generative AI applications as well as increased processing performance for HPC applications.

EC2 P6-B200 instances specifications
New EC2 P6-B200 instances provide eight NVIDIA B200 GPUs with 1440 GB of high bandwidth GPU memory, 5th Generation Intel Xeon Scalable processors (Emerald Rapids), 2 TiB of system memory, and 30 TB of local NVMe storage.

Here are the specs for EC2 P6-B200 instances:

Instance size GPUs (NVIDIA B200) GPU
memory (GB)
vCPUs GPU Peer to peer (GB/s) Instance storage (TB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
P6-b200.48xlarge 8 1440 HBM3e 192 1800 8 x 3.84 NVMe SSD 8 x 400 100

These instances feature up to 125 percent improvement in GPU TFLOPs, 27 percent increase in GPU memory size, and 60 percent increase in GPU memory bandwidth compared to P5en instances.

P6-B200 instances in action
You can use P6-B200 instances in the US West (Oregon) AWS Region through EC2 Capacity Blocks for ML. To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console.

Select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for p6-b200.48xlarge instances. The total number of days that you can reserve EC2 Capacity Blocks is 1-14 days, 21 days, 28 days, or multiples of 7 up to 182 days. You can choose your earliest start date for up to 8 weeks in advance.

Now, your EC2 Capacity Block will be scheduled successfully. The total price of an EC2 Capacity Block is charged up front, and the price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

When launching P6-B200 instances, you can use AWS Deep Learning AMIs (DLAMI) to support EC2 P6-B200 instances. DLAMI provides ML practitioners and researchers with the infrastructure and tools to quickly build scalable, secure, distributed ML applications in preconfigured environments.

To run instances, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs.

You can integrate EC2 P6-B200 instances seamlessly with various AWS managed services such as Amazon Elastic Kubernetes Services (Amazon EKS), Amazon Simple Storage Service (Amazon S3), and Amazon FSx for Lustre. Support for Amazon SageMaker HyperPod is also coming soon.

Now available
Amazon EC2 P6-B200 instances are available today in the US West (Oregon) Region and can be purchased as EC2 Capacity blocks for ML.

Give Amazon EC2 P6-B200 instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 P6 instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Enhanced remote desktop experience: Amazon DCV with Amazon Linux 2023

Post Syndicated from Madhur Kulkarni original https://aws.amazon.com/blogs/compute/enhanced-remote-desktop-experience-amazon-dcv-with-amazon-linux-2023/

Amazon DCV has evolved as a powerful remote display protocol, enabling secure high-performance remote desktop access and application streaming. This blog talks about how DCV remote display capabilities are now integrated with Amazon Linux 2023 (AL2023).

Overview

This post introduces new Graphical Desktop with AL2023 and provides an overview of new features available through DCV. The Graphical Desktop comes with GNOME 47 for a smooth UI experience that you can connect using DCV, enabling remote desktop access from anywhere. It also provides an overview of more tools such as a terminal emulator with Ptyxis for improved CLI experience, Mozilla Firefox for secure web browsing, an image viewer with Loupe, a text editor, and a file manager for file navigation, and.

Core features

AL2023 introduces an enhanced desktop experience, specifically tailored for remote access needs, as shown in the following Figure-1. DCV technology allows you to connect seamlessly to Graphical Desktop interface with GNOME 47. Users benefit from native DCV protocol support that enables high-performance remote access, featuring dynamic resolution adaptation and hardware-accelerated video encoding. Enhanced security features include advanced encryption and granular access controls.

Although DCV supports multiple desktop environments, the use of GNOME 47 is specifically part of the AL23 current release. The GNOME 47 system uses Mutter 47.0 as its window manager and compositor, alongside the GTK 4 toolkit for its user interface. This includes window management capabilities that provide more precise control over application placement and sizing, while improved multi-monitor support makes sure that workspaces expand seamlessly across displays. Most importantly, there is a native desktop-like experience with the DCV local features such as clipboard sharing, audio redirection, and multi-monitor capabilities, which deliver a seamless and responsive remote environment.

Figure 1. DCV desktop interface with AL2023

Ptyxis delivers exceptional performance with SSH, SFTP, and TLS/SSL support, as shown in the following figure. You can experience GPU-accelerated text rendering with a crystal-clear display, supporting UTF-8/16 and Unicode 15.0, while maintaining minimal input lag at 60 Hz refresh rates. The DCV 4K support enables high-resolution (3840 x 2160 pixels) remote desktop streaming, which allows users to work with graphically intensive applications while maintaining excellent visual quality. Ptyxis is deeply integrated with GNOME through D-Bus and GNOME I/O (GIO) interfaces, providing access to global search and system notifications. Users can use advanced session management with JSON-based configurations, tab groups, split views up to 16 panes, and automatic session restoration. The terminal includes full 256-color and true-color support, compatible with Bash, Zsh, and Fish shells, while maintaining robust connection stability.

Figure 2. Terminal Emulator

Firefox in AL2023 is optimized specifically for remote desktop scenarios, as shown in the following figure. The browser features hardware-accelerated rendering and WebGL 2.0 support, delivering smooth graphics and responsive page loading. Enhanced browser capabilities provide better performance for 3D applications and interactive web content. Users can experience optimized video playback with minimal frame drops and improved synchronization, which are particularly important for remote streaming needs. Integration with DCV streaming technology enables efficient resource usage and provides a local-like experience when accessing remote workstations, featuring seamless audio-video synchronization, smooth multi-monitor support, and native peripheral device integration.

Figure 3. Mozilla Firefox with DCV

More features

The GNOME Text Editor seamlessly integrates with AL2023, providing a modern, distraction-free interface for coding and text editing within the DCV environment, as shown in the following figure. As the default text editor in the AL23 GNOME desktop, it offers essential features such as syntax highlighting, dark/light themes, and autosave functionality, making it ideal for remote development work.

Figure 4. GNOME Text Editor

Loupe offers a sleek and intuitive image viewing experience in AL2023 when accessed through DCV, as shown in the following figure. It features a clean interface with smooth animations, efficient image loading, and gesture support, all while maintaining responsive performance over the DCV remote desktop connection. This makes it ideal for viewing and basic image manipulation tasks.

Figure 5. Image Viewer features and options

The GNOME File manager in AL2023 provides a robust and intuitive interface for managing files and folders when accessed through the DCV remote desktop environment, as shown in the following figure. It offers essential features such as drag-and-drop functionality, list and grid views, file search, and seamless integration with cloud storage, all while maintaining responsive performance over the DCV optimized remote connection protocol. You can use DCV to upload files to and download files from DCV session storage. For instructions on how to enable and configure session storage, go to Enabling session storage in the DCV Administrator Guide.

Figure 6. File Manager

Conclusion

The Amazon DCV team is committed to delivering the best remote desktop experience possible, and these enhancements demonstrate that commitment. In this post, we demonstrated how our integrated solution, from the GNOME 47 intuitive interface to the powerful terminal capabilities of Ptyxis, creates a seamless remote workspace. Using these improvements allows you to enhance productivity and overall user experience in remote desktop environments. These enhanced capabilities offer a significant step forward in remote computing, thereby providing tools and optimizations designed to meet the evolving needs of the distributed and flexible work environments today.

For a deeper dive into setup and advanced configurations, you should review our comprehensive DCV admin guides, which provide detailed information to help you maximize the potential of these new features.

AWS Weekly Roundup: South America expansion, Q Developer in OpenSearch, and more (May 12, 2025)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-south-america-expansion-q-developer-in-opensearch-and-more-may-12-2025/

I’ve always been fascinated by how quickly we’re able to stand up new Regions and Availability Zones at AWS. Today there are 36 launched Regions and 114 launched Availability Zones. That’s amazing!

This past week at AWS was marked by significant expansion to our global infrastructure. The announcement of a new Region in the works for South America means customers will have more options for meeting their low latency and data residency requirements. Alongside the expansion, AWS announced the availability of numerous instance types in additional Regions.

In addition to the infrastructure expansion, AWS is also expanding the reach of Amazon Q Developer into Amazon OpenSearch Service.

Last week’s launches

Instance announcements

AWS expanded instance availability for an array of instance types across additional Regions.

Additional updates

Upcoming events

We are in the middle of AWS Summit season! AWS Summits run throughout the summer in cities all around the world. Be sure to check the calendar to find out when a AWS Summit is happening near you. Here are the remaining Summits for May, 2025.


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Announcing second-generation AWS Outposts racks with breakthrough performance and scalability on-premises

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/announcing-second-generation-aws-outposts-racks-with-breakthrough-performance-and-scalability-on-premises/

Today we’re announcing the general availability of second-generation AWS Outposts racks, which marks the latest innovation from AWS for edge computing. This new generation includes support for the latest x86-powered Amazon Elastic Compute Cloud (Amazon EC2) instances, new simplified network scaling and configuration, and accelerated networking instances designed specifically for ultra-low latency and high-throughput workloads. These enhancements deliver greater performance for a broad range of on-premises workloads, such as core trading systems of financial services and telecom 5G Core workloads.

Customers like athenahealth, FanDuel, First Abu Dhabi Bank, Mercado Libre, Liberty Latin America, Riot Games, Vector Limited, and Wiwynn are already using Outposts racks for workloads that need to stay on-premises. The second-generation Outposts rack can provide low latency, local data processing, or data residency needs, such as game servers for multi-player online games, customer transaction data, medical records, industrial and manufacturing control systems, telecom Business Support Systems (BSS), and edge inference of a variety of machine learning (ML) models. Customers can now take advantage of the latest generation of processors and more advanced configurations of Outposts racks to support faster processing, higher memory capacity, and increased network bandwidth.

Latest generation EC2 instances

We’re excited to announce local support for the latest generation (7th generation) of x86-powered Amazon EC2 instances on AWS Outposts racks, starting with C7i compute-optimized instances, M7i general-purpose instances, and R7i memory-optimized instances. These new instances deliver twice the vCPU, memory, and network bandwidth while providing up to 40% better performance compared to C5, M5, and R5 instances on previous generation Outposts racks. They are powered by 4th Gen Intel Xeon Scalable processors and are ideal for a broad range of on-premises workloads requiring enhanced performance such as larger databases, more memory-intensive applications, advanced real-time big data analytics, high-performance video encoding and streaming, and CPU-based edge inference with more sophisticated ML models. Support for more latest generation EC2 instances, including GPU-enabled instances, is coming soon.

Simplified network scaling and configuration

We’ve completely reimagined networking in our latest Outposts generation, making it simpler and more scalable than ever. At the heart of this upgrade is our new Outposts network rack, which acts as a central hub for all your compute and storage traffic.

This new design brings three major benefits to the table. First, you can now scale your compute resources independently from your networking infrastructure, giving you more flexibility and cost efficiency as your workloads grow. Second, we’ve built in network resilience from the ground up, with the network rack automatically handling device failures to keep your systems running smoothly. Third, connecting to your on-premises environment and AWS Regions is now a breeze – you can configure everything from IP addresses to VLAN and BGP settings through straightforward APIs or our updated console interface.

Image of an AWS Outposts rack device

Specialized Amazon EC2 instances with accelerated networking

We’re introducing a new category of specialized Amazon EC2 instances on Outposts racks with accelerated networking. These instances are purpose built for the most latency-sensitive, compute-intensive, and throughput-intensive mission-critical workloads on-premises. To deliver the best possible performance, in addition to the Outpost logical network, these instances feature a secondary physical network with network accelerator cards connected to top-of-rack (TOR) switches.

First in this category are bmn-sf2e instances, designed for ultra-low latency with deterministic performance. The new instances run on Intel’s latest Sapphire Rapids processors (4th Gen Xeon Scalable), delivering 3.9 GHz sustained performance across all cores with generous memory allocation – 8GB of RAM for every CPU core. We’ve equipped bmn-sf2e instances with AMD Solarflare X2522 network cards that connect directly to top-of-rack switches.

For financial services customers, especially capital market firms, these instances offer deterministic networking through native Layer 2 (L2) multicast, precision time protocol (PTP), and equal cable lengths. This enables customers to meet regulatory requirements around fair trading and equal access while easily connecting to their existing trading infrastructure.

Instance Name vCPUs Memory (DDR5) Network Bandwidth NVMe SSD Storage Accelerated Network Cards Accelerated Bandwidth (Gbps)
bmn-sf2e.metal-16xl 64 512 GiB 25 Gbps 2 x 8 TB (16 TB) 2 100
bmn-sf2e.metal-32xl 128 1024 GiB 50 Gbps 4 x 8 TB (32 TB) 4 200

The second instance type, bmn-cx2, is optimized for high throughput and low latency. This instance features NVIDIA ConnectX-7 400G NICs physically connected to high-speed top-of-rack switches, delivering up to 800 Gbps bare metal network bandwidth operating at near line rate. With native Layer 2 (L2) multicast and hardware PTP support, this instance is ideal for high-throughput workloads like real-time market data distribution, risk analytics, and telecom 5G core network applications.

Instance Name vCPUs Memory (DDR5) Network Bandwidth NVMe SSD Storage Accelerated Network Cards Accelerated Bandwidth (Gbps)
bmn-cx2.metal-48xl 192 1536 GiB 50 Gbps 4 x 4 TB (16 TB) 2 800

Bottom line, the new generation of Outposts racks deliver enhanced performance, scalability, and resiliency for a broad range of on-premises workloads, even for mission-critical workloads with the most stringent latency and throughput requirements. You can make your selection and initiate your order from the AWS Management Console. The new instances maintain consistency with regional deployments by supporting the same APIs, AWS Management Console, automation, governance policies, and security controls in the cloud and on-premises, improving developer productivity and IT efficiency.

Things to know

At launch, second-generation Outposts racks can be shipped to US and Canada and be parented back to 6 AWS Regions including US East (N. Virginia and Ohio), US West (Oregon), EU West (London and France) and Asia Pacific (Singapore). Support for more countries and territories and AWS Regions is coming soon. At launch, second-generation Outposts racks locally support a subset of AWS services found in previous generation Outposts racks. Support for more EC2 instance types and more AWS services is coming soon.

To learn more, visit the AWS Outposts racks product page and user guide. You can also talk to an Outposts expert if you are ready to discuss your on-premises needs.

— Micah;


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

New Amazon EC2 Graviton4-based instances with NVMe SSD storage

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/new-amazon-ec2-graviton4-based-instances-with-nvme-ssd-storage/

Since the launch of AWS Graviton processors in 2018, we have continued to innovate and deliver improved performance for our customers’ cloud workloads. Following the success of our Graviton3-based instances, we are excited to announce three new Amazon Elastic Compute Cloud (Amazon EC2) instance families powered by AWS Graviton4 processors with NVMe-based SSD local storage: compute optimized (C8gd), general purpose (M8gd), and memory optimized (R8gd) instances. These instances deliver up to 30% better compute performance, 40% higher performance for I/O intensive database workloads, and up to 20% faster query results for I/O intensive real-time data analytics than comparable AWS Graviton3-based instances.

Let’s look at some of the improvements that are now available in our new instances. These instances offer larger instance sizes with up to 3x more vCPUs (up to 192 vCPUs), 3x the memory (up to 1.5 TiB), 3x the local storage (up to 11.4TB of NVMe SSD storage), 75% higher memory bandwidth, and 2x more L2 cache compared to their Graviton3-based predecessors. These features help you to process larger amounts of data, scale up your workloads, improve time to results, and lower your total cost of ownership (TCO). These instances also offer up to 50 Gbps network bandwidth and up to 40 Gbps Amazon Elastic Block Store (Amazon EBS) bandwidth, a significant improvement over Graviton3-based instances. Additionally, you can now adjust the network and Amazon EBS bandwidth on these instances by up to 25% using EC2 instance bandwidth weighting configuration, providing you greater flexibility with the allocation of your bandwidth resources to better optimize your workloads.

Built on AWS Graviton4, these instances are great for storage intensive Linux-based workloads including containerized and micro-services-based applications built using Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Container Registry (Amazon ECR), Kubernetes, and Docker, as well as applications written in popular programming languages such as C/C++, Rust, Go, Java, Python, .NET Core, Node.js, Ruby, and PHP. AWS Graviton4 processors are up to 30% faster for web applications, 40% faster for databases, and 45% faster for large Java applications than AWS Graviton3 processors.

Instance specifications

These instances also offer two bare metal sizes (metal-24xl and metal-48xl), allowing you to right size your instances and deploy workloads that benefit from direct access to physical resources. Additionally, these instances are built on the AWS Nitro System, which offloads CPU virtualization, storage, and networking functions to dedicated hardware and software to enhance the performance and security of your workloads. In addition, Graviton4 processors offer you enhanced security by fully encrypting all high-speed physical hardware interfaces.

The instances are available in 10 sizes per family, as well as two bare metal configurations each:

Instance Name vCPUs Memory (GiB) (C/M/R) Storage (GB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
medium 1 2/4/8* 1 x 59 Up to 12.5 Up to 10
large 2 4/8/16* 1 x 118 Up to 12.5 Up to 10
xlarge 4 8/16/32* 1 x 237 Up to 12.5 Up to 10
2xlarge 8 16/32/64* 1 x 474 Up to 15 Up to 10
4xlarge 16 32/64/128* 1 x 950 Up to 15 Up to 10
8xlarge 32 64/128/256* 1 x 1900 15 10
12xlarge 48 96/192/384* 3 x 950 22.5 15
16xlarge 64 128/256/512* 2 x 1900 30 20
24xlarge 96 192/384/768* 3 x 1900 40 30
48xlarge 192 384/768/1536* 6 x 1900 50 40
metal-24xl 96 192/384/768* 3 x 1900 40 30
metal-48xl 192 384/768/1536* 6 x 1900 50 40

*Memory values are for C8gd/M8gd/R8gd respectively

Availability and pricing

M8gd, C8gd, and R8gd instances are available today in US East (N. Virginia, Ohio) and US West (Oregon) Regions. These instances can be purchased as On-Demand instances, Savings Plans, Spot instances, or as Dedicated instances or Dedicated hosts.

Get started today

You can launch M8gd, C8gd and R8gd instances today in the supported Regions through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types. You can also visit the Graviton Getting Started Guide to begin your Graviton adoption journey.

— Micah;


How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

Powering generative AI/ML solutions with AWS Outposts Servers at Edge locations

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/powering-generative-ai-ml-solutions-with-aws-outposts-servers-at-edge-locations/

This post is written by Brian Daugherty, Principal Solutions Architect, Leonardo Queirolo, Senior Cloud Support Engineer, and Reet Kundu, Senior Cloud Support Engineer

Powering generative AI/ML solutions with AWS Outposts Servers at Edge locations

Many organizations are vigorously pursuing generative AI initiatives in the Amazon Web Services (AWS) cloud today because generative AI drive advances in productivity, efficiency, and innovation.

However, for some organizations, industries, and use-cases, there is a compelling need to deploy generative AI not only in the cloud, but also at the edge due to factors such as application latency and proximity to critical data.

AWS Outposts can help these organizations address this need by extending AWS services to the edge, such as generative AI services, while maintaining the same tooling and orchestration capabilities found in AWS Regions.

Industrial and manufacturing use-cases are a primary focus of AWS Outposts Servers, which can be deployed on-premises to minimize latency and make sure of stable connectivity between orchestration and control applications such as Manufacturing Execution Systems (MES) or Supervisory, Control, and Data Acquisition (SCADA) systems and the industrial processes they control.

This post explores how to use Outposts Servers to power generative AI solutions at the edge. The example use-case demonstrates real-time anomaly detection for industrial processes and an edge-based human machine interface including a small language model (SLM) with Retrieval-Augmented Generation (RAG) to guide operators on best practices for problem resolution. Although the use case is specific, the tools and methods can be applied to many other edge generative AI use cases.

For a hands-on experience to implement this solution using Outposts Servers, fill out this form with your contact information and we will get back to you with lab access. A detailed step-by-step guide to develop the hands-on example is available in this link.

Architecture overview

As depicted in the following diagram, the solution is distributed in three modules. The first module (1) guides you to establish low-latency, local connectivity to an MQTT broker within the same on-premises network as your lab Amazon Elastic Compute Cloud (Amazon EC2) instance. You configure essential AWS infrastructure (Amazon S3, AWS Secrets Manager, AWS Identity and Access Management (IAM)) to manage the deployment, authentication, and permissions of AWS IoT Greengrass components. You deploy a component to the existing Greengrass core device on your lab EC2 instance to retrieve synthetic Arduino sensor data from the broker using its Local Network Interface (LNI).
Figure 1 – Architectural diagram of the solution to perform low-latency, local inference through generative AI and ML models running on Outposts Servers

Figure 1 – Architectural diagram of the solution to perform low-latency, local inference through generative AI and ML models running on Outposts Servers

In the second module (2), you deploy a component that detects anomalies in sensor data in real-time. This component runs on the Outposts Server EC2 instance hosting the AWS IoT Greengrass core device, performing inference directly at the edge. You use synthetic Arduino sensor data to generate anomalies and observe them being detected by the model. You configure an IoT rule to send the anomaly count to the Amazon CloudWatch Dashboard in the Region. This provides centralized monitoring, while making sure that the raw data and any sensitive data remains processed locally at the edge where latency and connectivity are assured.

In the third module (3), you deploy a comprehensive edge computing solution to enhance operational visibility and decision-making capabilities at the local level. The solution includes a local dashboard that provides a real-time telemetry to display raw sensor data and detect anomalies. A Virtual Assistant is integrated with SLM to provide context-aware response from the factory data and forecasting capability to predict future anomaly trends.

Outposts Server

Outposts Servers provide fully managed AWS infrastructure, services, APIs, and tools for edge use-cases . Two form factors are available: 1U servers are AWS Graviton based, and 2U servers are third-generation Intel Xeon Scalable processor based.

Enabling anomaly detection at the edge

Outposts Servers allow local sensor data processing for low-latency anomaly detection and resilience against external connectivity issues, as shown in the following figure. The example uses synthetic Arduino devices with gyroscope sensors data, simulating industrial sensors sending data to an MQTT Broker on an EC2 instance in the Outposts Server. Gyroscope data is used in various monitoring systems, such as motion control systems, orientation detection, stability, and balance mechanism. The Lab EC2 instance fetches sensor data through the MQTT client and processes it using a machine learning (ML) model for anomaly detection.

Figure 2 – Architectural diagram showing data flow from Arduino sensors through MQTT broker and EC2 on Outposts Server to perform local inference

Figure 2 – Architectural diagram showing data flow from Arduino sensors through MQTT broker and EC2 on Outposts Server to perform local inference

Outposts server LNI

Local communication between synthetic Arduino sensor data, MQTT broker, and the Lab EC2 instance uses LNI, providing Layer 2 presence on the local network. The setup necessitates creating an Elastic Network Interface (ENI) on an Outposts subnet with the LNI enabled, attaching it to the Lab EC2 Instance, and verifying connectivity through the MQTT Broker’s LNI IP using the command ping -c 5 <MQTT_BROKER_LNI_IP> . This enables direct, low-latency communication between components crucial for this edge computing scenario.

AWS IoT Greengrass

AWS IoT Greengrass is an open source edge runtime and cloud service for device software management and deployment supported on Outposts Server. This hybrid approach combines the benefits of edge computing with centralized management, such as:

  • Centralized artifact management: store and version component artifacts in Amazon S3, enabling consistent deployment across multiple edge locations.
  • Secure configuration: use Secrets Manager to handle sensitive information and credentials unique to each edge location.
  • Fleet monitoring: use CloudWatch for centralized monitoring and logging across your distributed edge deployment.
  • Automated updates: deploy software updates and model improvements across your edge fleet through AWS IoT Greengrass component management.

AWS IoT Greengrass components, such as the one used for the anomaly detection, can be deployed to EC2 instances running on Outposts Servers. After configuring the Lab EC2 instance with Greengrass, you can download components from an S3 bucket. The first component deploys a subscriber for receiving synthetic Arduino sensor data through MQTT broker configuration, as shown in the following configuration line.

{
    "broker": "<MQTT_BROKER_LNI_IP>",
    "port": 1883,
    "client_id": "OutpostsServerMLEdge_<workshop-id>",
    "sensor_name": "ArduinoSensor_<arduino-id>",
    "topic": "arduino/ArduinoSensor_<arduino-id>/3-axis-rotation",
    "thing_name": "OutpostsServerMLEdge_Sub",
    "mqttauth_creds": "<ARN_SECRET_MQTT_CREDENTIALS>"
}

The second component is the Anomaly Detector artifact that processes sensor data in real-time, detects anomalies using a pre-trained model, and sends anomaly counts to AWS IoT Core. Key components include:

  • edge_application.py: script for processing sensor data, performing local inference using pre-trained model in ONNX format, and publishing anomaly counts to AWS IoT Core. It is used for local inference, so that the raw data is not exposed outside the Edge location.
  • model: directory storing “arduino.onnx”, a pre-trained Autoencoder model for anomaly detection.
  • statistics: directory storing the values of different statistical functions (for example, mean and standard deviation) from the training phase and used by edge_application.py for inference.
  • functions: directory storing the code of the functions, such as the code to publish to the AWS IoT Core.

After deployment of subscriber and detector components, the Lab EC2 instance processes synthetic gyroscope data from Arduino sensors, detecting anomalies during X, Y, or Z axis movement:

Real-time Dashboard showing sensor data and anomaly count

Real-time anomaly detection results from gyroscope sensor data across X, Y, and Z axes.

Building upon the foundation of Outposts Server, Local Network Interface (LNI), and AWS IoT Greengrass, this solution extends beyond anomaly detection to deliver comprehensive edge AI capabilities. These core components work together to enable advanced generative AI applications at the edge, as demonstrated in the following sections.

Edge generative AI applications with Outposts Server

The solution demonstrates the implementation of key edge generative AI capabilities:

  • Contextual virtual assistance: providing on-site personnel with AI-powered guidance and troubleshooting using local operational data, SOPs, and technical documentation.
  • Predictive insights: using foundational models (FMs) to forecast future trends based on historical data, enabling proactive planning and optimization.
  • Real-time operational dashboard: integrating sensor data visualization with AI-powered insights and forecasts in a unified local interface that maintains operations during connectivity interruptions.

1. Contextual virtual assistance at the edge

The solution implements the virtual assistant through an AWS IoT Greengrass component. The following is a snippet from the component recipe showing the key configuration parameters:

{
    "ComponentConfiguration": {
        "DefaultConfiguration": {
            // Workshop defaults, SLM runs locally on same EC2 instance
            "SLM_endpoint": "http://localhost:8080",  
            "embedding_model": "all-MiniLM-L6-v2",    
            "knowledge_base_directory": "Factory_Data" 
        }
    }
    // Additional component recipe configurations...
}

Although the solution demonstrates a streamlined setup with the SLM running on the same EC2 instance as the AWS IoT Greengrass component, the architecture enables flexible deployment options through the SLM_endpoint configuration. Organizations can:

  • Deploy the SLM on a dedicated resource in their on-premises network (for example "http://<LNI-IP-DEDICATED-RESOURCE>:8080")
  • Use existing hardware infrastructure accessible through LNI
  • Scale SLM compute resources independently from the AWS IoT Greengrass component
  • Maintain low-latency communication through local network interfaces

The implementation showcases a streamlined approach to RAG at the edge through three main components:

Knowledge base management: the solution uses Amazon S3 for document storage (PDFs, Markdown, text) with automatic edge deployment through AWS IoT Greengrass. Alternatively, you can also choose to store the documents in a local storage. A vector database, such as ChromaDB, handles local vector storage and similarity search, enabling efficient knowledge base updates with centralized control.

Flexible query processing: the implementation provides a streamlined interface for RAG management, allowing users to load site-specific knowledge bases and switch between basic SLM and RAG-enhanced responses with local context:

if prompt := st.chat_input("Question"):
if "db" in st.session_state:
        prompt = augmentPrompt(prompt, st.session_state["db"])
response = getStreamingAnswer(prompt, SLM_MODEL_ENDPOINT)

Modular SLM integration: The solution uses a standardized chat completion API, which allows for integration with different SLM deployments while maintaining a consistent interface across the edge fleet:

def getStreamingAnswer(question: str, endpoint: str):    
    chat_template = '<|user|>\n{input} <|end|>\n<|assistant|>'
    payload = {
        'messages': [{'content': f'{chat_template.format(input=question)}'}],
        'stream': True
    }
    SLM_URL = endpoint + '/v1/chat/completions'

This flexible architecture can be adapted for many industrial use-cases where latency and proximity to local data-sources and processes are critical.

2. Predictive insights using local models

The solution demonstrates forecasting capabilities using Chronos, a small and efficient time series forecasting model that can run entirely at the edge. The following solution implementation shows how to process historical data and generate predictions using Chronos on the AWS IoT Greengrass component deployed on Outposts Server:

# Load Chronos model locally on the Outposts Server
pipeline = ChronosPipeline.from_pretrained(
    "amazon/chronos-t5-small",
    device_map="cpu",
    torch_dtype=torch.bfloat16,
)
# Generate forecasts with confidence intervals
def predict_anomaly_count_data():
    forecast = pipeline.predict(
        context = torch.tensor(df["total_anomalies"]),
        prediction_length = pred_length,
        num_samples = n_samples,
        top_k = 50,
        top_p = 1.0,
    )
    
    # Calculate confidence bounds
    low, median, high = np.quantile(forecast[0].numpy(), [0.1, 0.5, 0.9], axis=0)

Although the solution uses sample data for the demonstration, this architecture allows organizations to process complex, real-time data at each edge location. Companies can choose to upload only aggregated metrics to CloudWatch or Amazon QuickSight for fleet monitoring and BI analysis, making sure that sensitive raw data remains secure at the edge.

3. Real-time operational dashboard

The solution showcases a resilient monitoring solution where all inter-component communication occurs within the local network and processing happens on the Outposts server, making sure of full functionality during external network interruptions. The dashboard is accessible through the LNI of the Outposts server, allowing local clients to maintain access through the LNI IP address even when connectivity to the Region is lost.

Through a unified interface, the dashboard provides:

  • Real-time visualization of sensor readings
  • Anomaly detection results from the local ML component
  • AI-powered insights from the local SLM
  • Trend forecasting from the Chronos model

Real-time Dashboard showing sensor data and anomaly count

Real-time Dashboard showing sensor data and anomaly count

Virtual Assistant leveraging Factory Data to provide contextualized answers

Virtual Assistant leveraging Factory Data to provide contextualized answers

Chronos forecasting anomaly count based on historical data

Chronos forecasting anomaly count based on historical data

Conclusion

The implementation demonstrates how AWS Outposts Server enables organizations to use both traditional ML and advanced generative AI capabilities at the edge for a variety of industrial and manufacturing use-cases where low-latency and proximity to sensitive or real-time data are business- and process-critical.

To get started with AWS Outposts and explore use cases like this edge AI solution, fill out this form and our team will contact you with lab access and additional guidance. For a detailed walkthrough of this specific edge AI example, refer to this step-by-step guide. For more information about AWS Outposts Server, see the AWS Outposts Server User Guide.

Anchoring AWS Outposts servers with AWS Direct Connect

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/anchoring-aws-outposts-servers-with-aws-direct-connect/

This post is written by Perry Wald, Principal GTM SA, Hybrid Edge, Eric Vasquez Senior SA Hybrid Edge, and Fernando Galves Gen AI Solutions Architect, Outposts

AWS Outposts is a fully managed service that extends AWS infrastructure, services, APIs, and tools to customer premises. Outposts servers launched in 2022, a 1U or 2U rack-mountable host, with the ability to run Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Container Service (Amazon ECS), as well as other appropriate smaller scale edge services such as AWS IoT Greengrass. This version of Outposts is primarily focused on bringing lower latency, AWS compute capabilities to the edge at many user locations.

During Outposts provisioning, you or AWS creates a service link connection that connects your Outposts server to your chosen AWS Region or home Region. Outposts depends on regional connectivity “to reach out to home,” needing very little in terms of networking. Looking at the network requirements, it needs:

  • DHCP, to assign an IP address and a default gateway
  • Public DNS, to resolve the name of the initial regional endpoint, to allow automated setup, and
  • Internet access, so that when the regional endpoint has been resolved, the Outpost can reach that endpoint. With a minimum of 500 Mbps or and a max of 175 ms round trip latency

User challenges with internet connectivity at the edge

When you order an Outposts server, you are responsible for installing the server. Outposts servers are self-provisioning and need a service link connection between your Outposts and the AWS Region (or home Region). This connection allows for the management of Outposts and the exchange of traffic to and from the AWS Region. Server deployment can be broken down into the following steps: installing the Outposts servers, powering them on, and providing authentication details through a command line. Then, the Outpost servers reach out to the regional endpoint, and provision themselves. Your Outpost status will show as Active when the process has completed, it could take a few hours depending on service link bandwidth.

Although this has been suitable for the vast majority of use cases, there are some locations that can’t provide internet connectivity in their environments. This has mostly been in use cases where there is a strong security reason for not having an internet connection (such as financial services kiosks, small manufacturing facilities, and defense), so as to avoid risks such as DDoS attacks and potential hack attempts, or to meet requirements for receiving an authority to operate (ATO).

These locations either have some form of direct connect, or more commonly have a centralized direct connect link to AWS, and an MPLS network linking all their remote sites to a central one. In both of these scenarios, the requirement is to allow the Outpost servers to resolve and reach the public endpoint for setup, and subsequently the public anchor endpoint for management. This is done without needing to leave the AWS ecosystem, without needing to expose themselves unnecessarily to potential internet threats, and without adding more systems to manage themselves, but rather making use of AWS services.

To meet this requirement, we identified several key things that need to be provided if the user does not have internet connectivity at the remote location, as follows:

  1. DHCP, to provide the Outposts servers with an IP address, default gateway, and DNS servers.
  2. Public DNS access to resolve both the setup endpoint, and when live, the anchor endpoint.
  3. Public internet access, without exposing the user location to potentially harmful traffic from the internet.

Direct Connect VIF options

There are three different types of Virtual Interfaces (VIF) possible to configure on an AWS Direct Connect link:

  • Public VIF: A public VIF can access all AWS public services using public IP addresses.
  • Private VIF: A private VIF should be used to access an Amazon Virtual Private Cloud (Amazon VPC) using private IP addresses.
  • Transit VIF: A transit VIF should be used to access one or more Amazon VPC Transit Gateways associated with Direct Connect gateways.

Transit VIF option

A transit VIF can be used to solve both of these issues. First, a transit VIF deploys an ENI within a VPC (known as an attachment), so that traffic coming from the transit VIF into a VPC can be routed. This is because it follows the rule that, for non-transitive VPC routing, the traffic has to either be sourced or targeted for an ENI in the VPC.

If the traffic is forwarded to a regional VPC through the transit gateway, then it can be forwarded to the internet through an NAT gateway. This is an enhancement of the architecture to use a transit gateway to provide a single egress point for multiple VPCs to the internet. For more information, see Creating a single internet exit point from multiple VPCs Using AWS Transit Gateway. In this case, instead of the transit gateway routing multiple VPCs to the internet, it’s routing to an on-premises connection.

Using a transit gateway to forward traffic to an NAT gateway allows you to provide internet connectivity for the Outposts servers without managing virtual appliances, because NAT gateway provides this as a service. NAT gateways also only allow outbound access, so they provide security against any attempted external access by a bad actor from the internet. This works for Outposts servers since they only need outbound access. Outposts always initiate communication to an anchor or service endpoint, and they never receive communication except as a response.

Architectural diagram showing the use of a Transit VIF and NAT gateway in a Region reaching regional endpoints

Figure 1. Architectural diagram showing the use of a Transit VIF and NAT gateway in a Region reaching regional endpoints

DNS provisioning

Although the preceding architecture solves the challenge of how we provide a path for IP packets to transit between the Outposts servers and the public endpoints needed, it doesn’t solve the issue of resolving DNS names. If the remote site is isolated from the internet, then it has no clear way to resolve DNS.

Amazon Route53 resolver endpoints allow you to deploy an IP address within a VPC subnet, which provides DNS resolution. There are two types of resolver endpoints: outbound and inbound.

Outbound resolver endpoints are used by AWS to send DNS queries to your on-premises DNS servers. Inbound resolver endpoints are used by your DNS servers (and hosts) to resolve addresses within Route 53.

Route 53 can resolve public DNS names, so the Outposts service endpoint outposts.<region-name>.amazonaws.com becomes resolvable by an inbound resolver endpoint.

Configuring the Outposts egress VPC

  1. Set up service link egress VPC, build subnets, deploy a NAT gateway, and transit gateway.
  2. Create Route 53 resolver inbound endpoint.
  3. Configure DHCP on the switch, and make sure that the DNS value matches resolver endpoint.
  4. Configure Transit VIF on the switch, build a BGP peer, and attach to your transit gateway.
  5. Confirm propagation settings on transit gateway and default routes.
  6. Confirm routes on subnets to allow traffic out to the internet, and back to your Outpost servers.
  7. Test name resolution (dig) and https (curl) test to service endpoint.
  8. If needed, install your Outpost servers.

Public VIF option

Using a public VIF allows you to provide an internet connection directly to the on-premises site. In turn, this means you need to implement firewalls and security functions on this connection, adding more layers of operational overhead. A public VIF also means that the on-premises end of the VIF can be accessed by any public IP on the AWS public network, regardless of the instance to which IP is mapped. A public VIF is a public IP endpoint on the AWS public network. You should treat public VIF traffic as internet-based traffic. This can become cumbersome for firewalls teams if they have to allow-list known AWS IP ranges and manage the stateful firewall for a long range of AWS IPs.

Furthermore, even if the user is happy to implement and manage a firewall on the end of that public VIF, there is still a question of how the Outpost would resolve DNS in this setup, and subsequent anchor endpoints. Unless the private network already has DNS resolution to a public DNS, then there are no DNS servers that DHCP can point to in order to allow the Outposts servers to get name resolution. This is because there is no public DNS endpoint within the AWS public network. Traffic from a user’s public VIF can access the AWS public network, but it can’t exit it to other public networks. For example, if the you had configured DHCP to point to one of the well-known DNS servers (such as 8.8.8.8), then, since this DNS servers lives outside of the AWS public network, requests originating from the on-premises side of a public VIF would be dropped as it hit the border of the AWS autonomous system.

The only way for a DNS request to be resolved would be to build a bind forwarding service within a VPC, provide it with a public IP address, and point the DHCP DNS values at this IP address.

This network configuration introduces complexity, and won’t be possible for those with highly regulated workloads. You would need to manage a firewall on-premises, allow a public network to reach the on-premises location, and manage a bind servers setup within a VPC. For these reasons, a public VIF is generally not an option unless the user is already running one, and is familiar with the steps to secure it.

Figure 2. Architectural diagram showing traffic flow using a public VIF and AWS Outposts

Private VIF option

A private VIF whether connected directly to a virtual private gateway (VGW), or through a Direct Connect gateway. VPCs do not support transitive routing. To explain this another way, any traffic following a routing rule in a subnet route table has to either originate from, or be destined for, an IP address (or to be more explicit, an Elastic Network Interface (ENI)) inside that VPC.

Virtual private gateways do not have an ENI associated with them, but are pointed to as a next hop within a subnet routing table. If we take this example and look at what the Outposts servers would be trying to pass as traffic, then it would send a packet with a source address of the Outposts servers, and a destination address of the Outposts service public endpoint (assuming that it could resolve it). When this packet reaches the VPC, then neither the source nor destination address would belong to an ENI within the VPC. Therefore, VPC routing would drop the packet.

Even if there was a routing rule on the subnet pointing the next hop for all traffic to a NAT gateway (ideal for internet egress), the routing still wouldn’t work. This is because the packet from the Outposts servers doesn’t have a destination of the NAT gateway, but instead a destination of the setup endpoint in the internet.

It’s possible to use a combination of ingress routing and transparent proxies to ingest the traffic and pass it to an instance running a proxy service to forward to the internet. However, this adds complexity having to manage and maintain proxy servers. For these reasons, a private VIF is generally not recommended.

Architectural diagram showing VGW and packet drops because of transitive routing not being supported

Figure 3. Architectural diagram showing VGW and packet drops because of transitive routing not being supported

Conclusion

In this post, we discussed architecture patterns you can use to provision your Outposts when public internet connectivity is unavailable. To get started with Outpost servers please visit our Server User Guide. For more information, contact us to learn more.

Migrating your on-premises workloads to AWS Outposts Rack

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/migrating-your-on-premises-workloads-to-aws-outposts-rack-2/

This post is written by Craig Warburton, Senior Solutions Architect, Hybrid; Sedji Gaouaou, Senior Solutions Architect, Hybrid; and Brian Daugherty, Principal Solutions Architect, Hybrid.

Migrating workloads to AWS Outposts Rack offers you the opportunity to gain the benefits of cloud computing while keeping your data and applications on premises.

For organizations with strict data residency requirements, by deploying AWS infrastructure and services on premises, you can keep sensitive data and mission-critical applications within your own data centers or facilities, helping ensure compliance with data sovereignty laws and regulatory frameworks.

On the other hand, if your organization does not have stringent data residency requirements, you may opt for a hybrid approach, using both Outposts Rack and the AWS Regions. With this flexibility, you can process and store data in the most appropriate location based on factors such as latency, cost optimization, and application requirements.

In this post, we cover options to migrate your workloads to an Outposts Rack, taking into account your specific data residency requirements. We explore strategies, tools, and best practices to enable a successful migration tailored to your organization’s needs.

Overview

AWS has several services to help you migrate and rehost workloads, including AWS Migration Hub, AWS Application Migration Service, AWS Elastic Disaster Recovery. Alternatively, you can use backup and recovery solutions provided by AWS partners.

At AWS, we use the 7 Rs framework to help organizations evaluate and choose the appropriate migration strategy for moving applications and workloads to the AWS Cloud. The 7 Rs represent:

  1. Rehosting (rehost or lift and shift)
  2. Replatforming (lift, tinker, and shift)
  3. Repurchasing (republish or re-vendor)
  4. Refactoring (re-architecting)
  5. Retiring
  6. Retaining (revisit)
  7. Relocating (remigrate).

This post focuses on rehosting and the services available to help rehost on-premises applications to Outposts Rack.

Before getting started with any migration, AWS recommends a three-phase approach to migrating workloads to the cloud (AWS Region or Outposts Rack). The three phases are assess, mobilize, and migrate and modernize.

Figure 1: Diagram showing the three migration phases of assess, mobilize, and migrate and modernize

Figure 1: Diagram showing the three migration phases of assess, mobilize, and migrate and modernize

This post describes the steps that you can take in the migrate and modernize phase. However, the assess and mobilize phases are also critical to allow you to understand what applications are migrated, the dependencies between them, and the planning associated with how and when migration occurs.

Workload migration to Outposts Rack: With staging environment in a Region

After deploying an Outposts Rack to your desired on-premises location, you can perform migrations of on-premises systems and virtual machines using either Application Migration Service and AMI creation or third-party backup and recovery services. Both scenarios are described in the following sections.

Scenario 1: Using Application Migration Service with AMI creation

Application Migration Service is able to lift and shift a large number of physical or virtual servers without compatibility issues, performance disruption, or long cutover windows.

In this scenario, at least one Outposts Rack is deployed on premises with the following prerequisites:

  • An AWS Replication Agent installed on each source server
  • At least one Outposts Rack installed and activated
  • VPC in an AWS Region
  • Staging subnet for staging migrated instances
  • Cutover subnet to validating migrated instances
  • Extended VPC spanning Region to the Outposts Rack
  • Migrated resources subnet where instances will be deployed from AMIs

The following diagram shows the solution architecture including the prerequisites and the on-premises servers that will be migrated to the Outposts Rack.

Figure 2: Architecture diagram showing migration with Application Migration Service

Figure 2: Architecture diagram showing migration with Application Migration Service

Step 1: Outposts Rack configuration

You can work with AWS specialists to size your Outposts for your workload and application requirements. In this scenario, you don’t need additional Outposts Rack capacity for migration because the staging area will be deployed in the Region (see 1 in Figure 2).

Step 2: Prepare Application Migration service

Set up Application Migration Service from the console in the Region to which your Outposts Rack is anchored. If this is your first setup, then choose Get started on the Application Migration Service console. When creating the replication settings template, ensure that your staging area is using subnets in the anchor Region (see 2 in Figure 2).

Step 3: Install the AWS Replication Agent to the source servers or machines

For large migrations, source servers may have a wide variety of operating system versions and may be distributed across multiple data centers. Application Migration Service offers the MGN connector, a feature that allows you to automate running commands on your source environment. Finally, ensure that communication is possible between the agent and Application Migration Service (see 3 in Figure 2).

In the following image, there is an example of deploying the AWS Replication Agent providing the necessary parameters (AWS Region, AWS access key and AWS secret access key).

Figure 2: Architecture diagram showing migration with Application Migration Service

When the AWS Replication Agent is installed, the server is added to the Application Migration Service console. Next, it undergoes the initial syncronization process, which is completed when showing the Ready for testing lifecycle state in the Application Migration Service console.

Step 4: Configure launch settings

Prior to testing or cutting over an instance, you must configure the launch settings by creating Amazon Elastic Compute Cloud (Amazon EC2) launch templates, ensuring that your cutover subnet is selected and that you choose an available instance type (see 4 in Figure 2). The instance type right-sizing feature allows AWS Application Migration Service to launch a test or cutover instance type that best matches the hardware configuration of the source server, by selecting the Basic option, AWS Application Migration Service will launch a test or cutover AWS instance type that best matches the OS, CPU, and RAM of your source server.

Step 5: Install AWS Systems Manager Agent on your cutover instances. When the launch settings are defined, you must activate the post-launch actions for either a specific server or all the servers. You must leave the Install the Systems Manager agent and allow executing actions on launched servers option toggled on in order for post-launch actions to work. Untoggling the option would disallow Application Migration Service to install the AWS Systems Manager Agent on your servers, and post-launch actions would no longer be executed (see 5 in Figure 2).

Figure 3: Post-launch actions on the Application Migration Service console

Figure 3: Post-launch actions on the Application Migration Service console

Step 6: Testing and cutover in Region

When you have configured the launch settings for each source server, you are ready to launch the servers as test instances. Best practice is to test instances before cutover.

Figure 4: Application Migration Service console ready to launch test instances

Figure 4: Application Migration Service console ready to launch test instances

Finally, after completing the testing of all the source servers, you are ready for cutover (see 6 on Figure 2). Prior to launching cutover instances, check that the source servers are listed as Ready for cutover under Migration lifecycle and Healthy under Data replication status.

Figure 5: Application Migration Console ready for cutover

Figure 5: Application Migration Console ready for cutover

To launch the cutover instances, choose the instances you want to cutover and then choose Launch cutover instances under Cutover (see Figure 5). The Application Migration Service console indicates Cutover finalized when the cutover has completed successfully the chosen source servers’ Migration lifecycle column shows the Cutover complete status, the Data replication status column shows Disconnected, and the Next step column shows Mark as archived. The source servers have now been successfully migrated into AWS. You can now archive your source servers that have launched cutover instances.

Step 7: Create a Migration AMI

After migrating all your workloads in the region where the Outposts is anchored to, create Amazon Machine Images (AMI). When you create an AMI from an instance, Amazon EC2 powers down the instance before creating the AMI to make sure that everything on the instance is stopped and in a consistent state during the creation process. If you are confident that your instance is in a consistent state appropriate for AMI creation, you can tell Amazon EC2 not to power down and reboot the instance.

This step can be automated using an existing Post Launch Action.

Step 8: Launch instances on AWS Outposts

The final part is to launch your created AMIs to your Outposts. To identify the EC2 instances configured on your Outpost you can use the following AWS Command Line Interface (AWS CLI):

Outposts get-outpost-instance-types \

–outpost-id op-abcdefgh123456789

The output of this command lists the instance types and sizes configured on your Outpost:

InstanceTypes:

– InstanceType: c5.xlarge

– InstanceType: c5.4xlarge

– InstanceType: r5.2xlarge

– InstanceType: r5.4xlarge

With knowledge of the instance types configured, you can now determine how many of each are available. For example, the following AWS CLI command, which is run on the account that owns the Outpost, lists the number of c5.xlarge instances available for use:

aws cloudwatch get-metric-statistics \

–namespace AWS/Outposts \

–metric-name AvailableInstanceType_Count \

–statistics Average –period 3600 \

–start-time $(date -u -Iminutes -d ‘-1hour’) \

–end-time $(date -u -Iminutes) \

–dimensions \

Name=OutpostId,Value=op-abcdefgh123456789 \

Name=InstanceType,Value=c5.xlarge

This command returns:

Datapoints:

– Average: 10.0

Timestamp: ‘2024-04-10T10:39:00+00:00’

Unit: Count

Label: AvailableInstanceType_Count

The output indicates that there were (on average) 10 c5.xlarge instances available in the specified time period (one hour). Using the same command for the other instance types, you discover that there are also 20 c5.4xlarge, 10 r5.2xlarge, and 6 r5.4xlarge available for use in completing the necessary EC2 launch templates.

Scenario 2: Using partner backup and replication solutions

You may already be using a third-party or AWS Partner solution to create on-premises backups of bare-metal or virtualized systems. These solutions often use local disk-arrays or object stores to create tiered backups of systems covering restore-points going back years, days, or just a few hours or minutes.

These solutions may also have inherent capabilities to restore from these backups directly to the AWS. This enables migration of on-premises systems to EC2 instances deployed to Outposts Rack.

In the scenario illustrated in Figure 6, the partner backup and replication service (BR) creates backups (see 1 in Figure 6) of virtual machines to on-premises disk or object storage repositories. Using the service’s AWS integration, virtual machines can be restored (see 2 in Figure 6) to an EC2 instance deployed on Outposts Rack, which is also on-premises. The restoration may follow a process that uses helper instances and volumes (see 3 in Figure 6) during intermediate steps to create Amazon Elastic Block Store (Amazon EBS) snapshots (see 4 in Figure 6) and then AMIs of the systems being migrated (see 5 in Figure 6), which are ultimately deployed (see 6 in Figure 6) to Outposts Rack.

Figure 6: Architecture diagram of the partner backup and replication scenario

Figure 6: Architecture diagram of the partner backup and replication scenario

When deploying an AMI created from a restored instance you must specify the target VPC and subnet. These should be the VPC being extended to the Outpost and a subnet that has been created in that VPC on the Outpost. You also need to specify an EC2 instance type that is available on the Outpost, which can be discovered using the process described in the previous section.

Workload migration to Outposts Rack using AWS Elastic Disaster Recovery (DRS)

Data residency can be a critical consideration for organizations that collect and store sensitive information, such as personally identifiable information (PII), financial data, or medical records. AWS Elastic Disaster Recovery, supported on Outposts Rack, helps enable seamless replication of on-premises data to Outposts Rack and addresses data residency concerns by keeping data within your on-premises environment, using Amazon EBS and Amazon S3 on Outposts.

In this scenario, an Outpost Rack is deployed on-premises with the following prerequisites:

  • At least one Outposts Rack installed and activated
  • The Outposts Rack must be in Direct VPC Routing (DVR) mode
  • VPC extended to the Outposts Rack containing subnets for staging and target resources
  • Amazon S3 on Outposts (necessary for all Elastic Disaster Recovery replication destinations)
  • An AWS Replication Agent installed on each source server

The following diagram shows the solution architecture and includes the on-premises servers that are migrated from the local network to the Outposts Rack. It also includes the staging VPC used to deploy the replication servers on Outposts Rack, Amazon S3 on Outposts to store the local Amazon EBS snapshots, and the target VPC extended to Outposts Rack.

Figure 7: Architecture diagram for workflow migration to Outposts Rack

Figure 7: Architecture diagram for workflow migration to Outposts Rack

Step 1: Outposts Rack configuration

To use Elastic Disaster Recovery on Outposts Rack, you need to configure both Amazon EBS and Amazon S3 on Outposts to support continuous replication and point-in-time recovery for your workload needs (see 1 in Figure 7). Specifically, you need to size the Amazon EBS and Amazon S3 on Outposts capacity according to your workload capacity requirements and application interdependencies. To do this, you can define dependency groups: each dependency group is a collection of applications and their underlying infrastructure with technical or non-technical dependencies. A 2:1 ratio is recommended for the EBS volumes to be used for near-continuous replication, and a 1:1 ratio is recommended for the Amazon S3 on Outposts ratio for EBS snapshots. For example, to migrate 40 TB of workloads, you need to plan for 80 TB of EBS volumes and 40 TB of Amazon S3 on Outposts capacity.

Step 2: Extend VPC to your Outposts Rack

When your Outpost has been provisioned and is available, extend the necessary Amazon Virtual Private Cloud (Amazon VPC) connection to the Outpost from the Region by creating the desired staging and target subnets (see 2 in Figure 7).

Step 3: Prepare Elastic Disaster Recovery service

Prepare the Elastic Disaster Recovery service from the Console to set the default replication and launch settings. When defining these settings, make sure that the Outposts resources available are chosen for staging and target subnets and instance and storage type (see 3 in Figure 7).

Step 4: Install the AWS Replication Agent to the source servers or machines

The next phase is to install the AWS Replication Agent to the source servers and to make sure that communication is possible between the AWS Replication Agent and your Outposts replication subnet through the Outposts local gateway, which makes sure that replication traffic uses the local network (see 4 in Figure 7).

Step 5: Continuous block-level replication

Staging area resources are automatically created and managed by Elastic Disaster Recovery. When the AWS Replication Agent has been deployed, continuous block-level replication (compressed and encrypted in transit) occurs (see 5 in Figure 7) over the local network.

Step 6: Launch Outposts Rack resources

Finally, migrated instances can now be launched using Outposts Rack resources based on the launch settings defined previously (see 6 in Figure 7).

Conclusion

In this post, you have learned how to migrate your workloads from your on-premises environment to AWS Outposts Rack based on your specific data residency requirements. When you have the flexibility of using AWS Regional services, AWS migration services or partner solutions can be used with infrastructure already in place. If your data must stay on-premises, then using AWS Elastic Disaster Recovery allows you to migrate your data without using Regional services, allowing you to migrate to Outposts Rack without your data leaving the boundary of a certain geographic location.

To learn more about an end-to-end migration and modernization journey, visit the AWS Migration Hub.

Implementing a serverless architecture to detect absence of Guardrails in Amazon Bedrock inference API calls

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/implementing-a-serverless-architecture-to-detect-absence-of-guardrails-in-amazon-bedrock-inference-api-calls/

This post is written by Sayan Chakraborty, Senior Solutions Architect, AWS

Implementing a serverless architecture to detect absence of Guardrails in Amazon Bedrock inference API calls

In today’s rapidly evolving artificial intelligence (AI) landscape, organizations are increasingly harnessing the power of foundation models through Amazon Bedrock to build sophisticated generative AI applications. Although this technology opens up exciting possibilities, it also brings forth important considerations around responsible AI implementation and content safety.

Amazon Bedrock Guardrails serve as a crucial safeguard, helping organizations filter out harmful content, prevent prompt injection attacks (LLM01:2025 from OWASP Top 10 for generative AI), and maintain ethical AI practices. These configurable safeguards are essential for enterprises committed to responsible AI development, especially when scaling their applications across various use cases.

However, there’s a critical consideration: although Guardrails are powerful, they’re optional by default in Amazon Bedrock inference API calls. For organizations that mandate the use of Guardrails as part of their responsible AI strategy, a solution is needed to make sure of consistent implementation across all API requests.

In this post, we explore how to build a serverless architecture that automatically detects when Guardrails are absent in Amazon Bedrock inference API calls. We demonstrate how enterprises can implement automated monitoring and alerting systems to maintain compliance with their AI safety standards, making sure that Guardrails are properly implemented wherever needed. This solution is particularly valuable for organizations prioritizing secure and responsible AI deployment at scale.

Prerequisites

Before proceeding with the implementation, make sure that you do the following:

1.Create an AWS account if you do not already have one, and log in. The AWS Identity and Access Management (IAM) user that you use must have sufficient permissions to make necessary AWS service calls and manage AWS resources.

2.Have AWS Command Line Interface (AWS CLI) installed and configured.

3.Have Git Installed.

Architecture

The following diagram shows an event-driven architecture of this solution.

Figure 1: Solution architecture diagram

Figure 1: Solution architecture diagram

Amazon Bedrock supports model invocation logging. When enabled, it collects the full request data, response data, and metadata associated with all model invocation calls performed in your AWS account. Logging can be configured to send the logs to supported destinations such as Amazon CloudWatch Logs and Amazon S3. This solution uses an S3 bucket to collect these logs. Note that this solution supports the below Amazon Bedrock inference APIs:

As logs get stored in the S3 bucket, an Amazon S3 event notification is generated to an Amazon EventBridge event bus. A rule that matches “Object Created” events from Amazon S3 routes these events to an AWS Step Functions state machine, which defines the orchestration logic to inspect the model invocation logs for missing Guardrails, and sends out an alert to a monitored email address when applicable.

Walkthrough of the orchestration

As mentioned previously, the Step Functions state machine is the orchestration engine that performs the business logic for this solution, as events are received from new logs created in the S3 bucket. When opened in the Workflow studio in the Step Functions console, you should observe the following diagram.

Figure 1: Step Functions state machine diagram as seen in workflow studio

Figure 2: Step Functions state machine diagram as seen in workflow studio

1.The first step in the state machine is to call an AWS Lambda function to get the logs from the S3 bucket using the bucket name and object key supplied in the event object received from EventBridge.

2.If the log shows that the Amazon Bedrock API invocation was successful, then the state machine collects the output object of the API response from the log that is needed for further evaluation.

3.The next step is to check if Amazon Bedrock Guardrails was used. This is done by looking for specific objects in the Amazon Bedrock API output that was captured from the logs.

4.If a Guardrail was detected, then the flow completes successfully, and no further action is needed.

5.If a Guardrail was not detected, then the next step in the state machine collects a few pieces of information from the log file that is necessary to record the transaction and adds the transaction date. Then, the transaction is logged in to the transactions table in Amazon DynamoDB.

6.A user or a role may be making a lot of API calls to Amazon Bedrock each day. Therefore, the solution implements a mechanism to prevent the monitored email address from being swamped by emails reporting the same user or role more than once each day. This is done in parallel to Step 5, where the flow checks if the principal’s identity (user ID/IAM role) is recorded as notified in the current date, by querying the notifications table in DynamoDB. If no results were found, meaning that a notification hasn’t been sent yet, then an email is sent out to a monitored email address through an Amazon Simple Notification Service (Amazon SNS) topic. Furthermore, an item is inserted into the notifications table in DynamoDB to prevent sending more notifications on the same day for the same principal.

Solution deployment

For deployment instructions, follow along in the GitHub repo or use this post. An AWS CloudFormation template is provided to deploy the solution.

1.Create an S3 bucket to store the model invocation logs from Amazon Bedrock. Under bucket Properties, turn the EventBridge notifications to On. This enables Amazon S3 to send an event notification to the EventBridge default event bus whenever a log file is created in the bucket by Amazon Bedrock.

2.Go to the Amazon Bedrock console and enable Model invocation logging under Bedrock Configuration > Settings, from the left navigation pane. Specify the bucket created in Step 1 under S3 location.

Figure 2: Amazon Bedrock settings for Model invocation logging

Figure 3: Amazon Bedrock settings for Model invocation logging

3. Create two more S3 buckets: one that is used by the Step Functions state machine to store Bedrock model invocation errors detected from the log, and the other that stores the Lambda function code for this solution. Inside the latter bucket, create a Folder called code (or any other preferred name) and upload the ZIP archive under the lambda-code folder of this repository, into that Amazon S3 folder. Note the names for these two S3 buckets and the Amazon S3 object key for the Lambda ZIP file. These must be specified as input parameters to the CloudFormation template.

4. From the CloudFormation console or using CLI, create a stack using the template provided in this repository called bedrock-guardrails-detection-template.yaml. For inputs, specify the BedrockLogsBucket (from Step 1), BedrockLogsErrorBucket (from Step 3), LambdaFunctionCodeBucket (from Step 3), LambdaFunctionCodeBucketKey (S3 object key for the ZIP file uploaded in Step 3, for example code/get-bedrock-logs-from-s3.py.zip), and NotificationEmailAddress (email address to subscribe to the SNS topic). It may take a few minutes to complete deployment of the CloudFormation stack.

5. When deployment is complete, access the email inbox for the email address specified during the CloudFormation stack deployment, and confirm the subscription using the email sent from the Amazon SNS topic. The email should be titled: AWS Notification – Subscription Confirmation. Choose the Confirm subscription link inside the email to complete the subscription process. The email account is now ready to receive notifications from this solution.

Scaling to multiple AWS accounts

The architecture discussed previously shows how Guardrails can be detected from within the same AWS account where Amazon Bedrock APIs are invoked. However, in most production environments, there are multiple AWS accounts where independent teams may be deploying their own generative AI workloads using Amazon Bedrock in their own accounts. To collect model invocation logs from all those accounts, EventBridge can be configured to send events from event buses in separate source workload accounts to a central event bus deployed in a central destination governance account. This central event bus can have a rule to route events to the Step Functions state machine deployed in that central governance account. The deployment model looks like the following diagram.

To learn more about sending and receiving events between AWS accounts in EventBridge, refer to the documentation.

Figure 3: Cross-account guardrail detection solution

Figure 4: Cross-account guardrail detection solution

Further considerations and clean up

Amazon Bedrock model invocation logging captures requests and responses from model invocations and stores the logs in the destination of your choosing. In this sample it is in an S3 bucket that you create. The following are some more security considerations.

1.To protect information, you may choose to use to encrypt the contents using server-side encryption with AWS KMS keys (SSE-KMS) on the S3 bucket, and specify a customer managed encryption key. More details are in this Amazon Bedrock user guide.

2.Perform regular cleanup of the model invocation logs bucket using an Amazon S3 lifecycle configuration rule as mentioned in this post.

To avoid ongoing charges, clean up your environment by following these steps to delete the resources you created by following this post, if they are no longer needed:

1.Delete the stack:
aws cloudformation delete-stack –stack-name STACK_NAME

2.Confirm the stack has been deleted:
aws cloudformation list-stacks –query “StackSummaries[?contains(StackName,’STACK_NAME’)].StackStatus”

3.Empty contents of the S3 buckets created manually as a prerequisite to deploying the CloudFormation stack and delete the buckets.

4.Turn off model invocation logging from under Settings in the Amazon Bedrock console, if it’s not desired any longer.

Conclusion

This post discussed implementing a serverless event-driven architecture to detect the absence of Guardrails in Amazon Bedrock inference API calls. As organizations increasingly use foundation models through Amazon Bedrock for generative AI applications, making sure of responsible AI implementation becomes crucial.

The solution presents an event-driven architecture that automatically detects when Guardrails are missing in API calls. It uses the Amazon Bedrock model invocation logging, storing logs in an Amazon S3 bucket. When new logs are created, an Amazon S3 event notification triggers an Amazon EventBridge event bus, which routes events to an AWS Step Functions state machine. Then, the state machine inspects the logs for missing Guardrails and sends alerts through Amazon SNS to a monitored email address.

The architecture includes features to prevent notification flooding and can scale across multiple AWS accounts. The post provides detailed deployment instructions using AWS CloudFormation and includes security considerations and cleanup procedures. With this solution you can help your organization maintain compliance with AI safety standards while scaling generative AI applications.

Efficiently manage Amazon EC2 On-Demand Capacity Reservations (ODCRs) with split, move, and modify

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/efficiently-manage-amazon-ec2-on-demand-capacity-reservations-odcrs-with-split-move-and-modify/

This post is written by Ninad Joshi, Senior Solutions Architect, Ballu Singh, Principal Solutions Architect, and Ankush Goyal, Enterprise Support Lead AWS.

Introduction

In today’s cloud-first world, managing compute capacity efficiently while making sure of application availability is crucial for your business. Amazon EC2 On-Demand Capacity Reservations (ODCR) is a valuable tool for organizations looking to manage their reservations, but managing reservations across multiple teams and accounts is challenging. Recently, AWS introduced new capabilities – split, move, and modify – that improve how organizations can manage their Capacity Reservations. In this post, we explore how these features can transform your operations.

Common ODCR management challenges

As a consumer of ODCR, you might face several challenges managing your Capacity Reservations. These challenges include but are not limited to the following:

  • Underused reserved capacity in some accounts
  • Inability to redistribute excess capacity efficiently
  • Difficulty in managing existing capacity across multiple AWS accounts
  • Difficulty in modifying reservation attributes post-creation

With multiple development teams and various projects running simultaneously, you might struggle with efficient capacity allocation. You might also find yourself dealing with situations where one team has excess capacity while another desperately needs it.

Use case 1: Redistributing capacity across teams

The unused capacity dilemma

Consider a scenario where your machine learning (ML) team has an ODCR for ten c5.2xlarge instances, but they’re only using five. Meanwhile, your Analytics team urgently needs three Amazon Elastic Compute Cloud (Amazon EC2) instances of the same type for a new project. Previously, your Analytics team would have had to create a new reservation, leading to unnecessary overhead of managing their own Capacity Reservation. Meanwhile, the five unused capacity slots of the ODCR owned by your ML team results in unnecessary costs.

Split capability to the rescue

Using the new split capability, you can now divide the existing ODCR (see ODCR-1 in the following figure), which has a total capacity of ten EC2 instances, and create a new ODCR with three of the unused capacity.

Before split, ODCR-1 with original total and unused capacity

Figure 1: Before split, ODCR-1 with original total and unused capacity

This results in the creation of two ODCRs:

  1. Original ODCR: total capacity of seven instances for the ML team
  2. New ODCR: three instances for the Analytics team

The following figure illustrates the split result:After split, ODCR-1 with updated total and unused capacity, and newly created ODCR-2

Figure 2: After split, ODCR-1 with updated total and unused capacity, and newly created ODCR-2

Sharing across accounts

The split operation creates the new ODCR in the same AWS account. If your teams operate under the same AWS account, then the split operation is direct without any further steps. However, if your teams use different AWS accounts, then you would need to use AWS Resource Access Manager (AWS RAM) to share the newly created ODCR after the split operation. This enables cross-account capacity management while maintaining centralized control.

Refer to the AWS Documentation for more information on pre-requisites and considerations when splitting off capacity from one reservation to a new one.

Refer to the API and CLI documentation for further information on the split capability such as parameters, exceptions, and limits.

Use case 2: moving capacity between reservations

Scaling for growth

After a few days, when your Analytics team needs one more capacity to launch an instance for their expanding project, you need to add more capacity to ODCR-2.

Move capability to the rescue

Instead of creating a new ODCR for this purpose, you can move one of the unused slots from ODCR-1 to ODCR-2. This flexibility saves you multiple steps involved in reserving new capacity, removes any disruptions to running existing workloads, and helps with simpler ODCR management. This rebalancing makes sure of optimal resource usage without further procurement.

Before move, ODCR-1 with unused capacity and ODCR-2 with current capacity

Figure 3: Before move, ODCR-1 with unused capacity and ODCR-2 with current capacity

After move, ODCR-1 with reduced capacity and ODCR-2 with additional capacity

Figure 4: After move, ODCR-1 with reduced capacity and ODCR-2 with additional capacity

Refer to the AWS Documentation for more information on pre-requisites and considerations when moving capacity from one reservation to another one.

Refer to the API and CLI documentation for further information on the move capability such as parameters, exceptions, and limits.

Use case 3: adjusting reservation attributes for changing workload patterns

Dynamic workload requirements

When your data processing workload patterns change significantly, you must adapt. Initially, you might have set up your ODCR with specific instance matching criteria, making it a targeted reservation for predictable workloads. However, as you introduce more dynamic, impromptu analysis projects, you need more flexibility in how instances can be launched against your reservation.

Modify feature to the rescue

Using the modify capability, you can now change the reservation’s attributes without creating a new reservation or disrupting running workloads. You can modify your ODCR by:

  • Changing instance quantity
  • Changing instance eligibility from Targeted to Open
  • Adjusting the reservation’s end date to align with your project timeline

This modification allows you to:

  • Launch new instances more flexibly without strict instance eligibility
  • Improve the usage of reserved capacity across different projects
  • Maintain cost optimization while adapting to changing business needs

The modify feature provides this flexibility while making sure that your existing workloads continue running uninterrupted, making it an invaluable tool for dynamic environments. See the following figures for an example where the instance quantity of ODCR-2 is modified from four to six:

Before modify, ODCR-2 with total capacity of four and instance eligibility of targeted

Figure 5: Before modify, ODCR-2 with total capacity of four and instance eligibility of targeted

After modify, ODCR-2 with new total capacity of six and instance eligibility of open

Figure 6: After modify, ODCR-2 with new total capacity of six and instance eligibility of open

Increasing ODCR size or creating a new one is subject to capacity availability in Amazon EC2 on-demand availability. Therefore, if unused capacity is available in an existing ODCR, then moving/splitting that could be a better option than modifying an ODCR.

Refer to the AWS Documentation for more information on pre-requisites and considerations when modifying Capacity Reservations.

Refer to the API and CLI documentation for further information on the modify capability such as parameters, exceptions, and limits.

Special considerations for split capacity

In the preceding sections, we saw how you can use the split capability to detach excess unused capacity to create an ODCR for another team. However, you can also use this capability to split used capacity to create new ODCRs. This capability is particularly helpful when you want to split partially used ODCRs to create a new one for easier tracking and management. Along with the considerations for splitting unused/excess capacity, the following considerations apply for splitting used capacity:

  1. The used capacity can only be split for an ODCR with open instance eligibility that isn’t shared with any account.
  2. The instances running inside the reservation are of open eligibility (in other words they are not targeting the reservation).
  3. When you split the used capacity, the eligible instances are randomly selected. You cannot specify which running instances are split. If a sufficient number of eligible instances aren’t found to fulfill the split quantity, then the split operation fails. When you specify the quantity of instances to be split, by default any unused capacity is moved first, followed by any eligible running instances (the used capacity in your reservation).

In the next section we different scenarios where you can or can’t use split capability.

Scenario 1: managing internal ODCRs (Capacity Reservation not shared with any other AWS account)

For your internal projects, when managing ODCRs that aren’t shared with external partners (other AWS accounts) and all have open instance eligibility, consider this example with ODCR-1:

  • Total capacity of ten c5.2xlarge instances, all with open instance eligibility
  • Eight instances currently in use by your ML team
  • Two unused instances

Before split, ODCR-1 with total capacity of 10 and 2 unused instances

Figure 7: Before split, ODCR-1 with total capacity of 10 and 2 unused instances

This ODCR isn’t shared with any external AWS accounts, thus you have maximum flexibility in splitting the reservation. You can split up to nine instances into a new reservation (total capacity minus one), regardless of how many instances are currently in use. In this scenario, you can share used as well as unused capacity. This gives you significant freedom in restructuring the capacity allocation for your internal teams.

After split, ODCR-1 remains with total capacity of one, and ODCR-2 with total capacity of nine with two unused capacities

Figure 8: After split, ODCR-1 remains with total capacity of one, and ODCR-2 with total capacity of nine with two unused capacities

Scenario 2: managing shared ODCRs with partners (Capacity Reservation shared with other AWS account)

When you need to share your ODCR with a partner’s AWS account, consider this scenario where ODCR-1 has:

  • Total capacity of ten c5.2xlarge instances
  • Eight instances in use by both your team and your partner’s team
  • Two unused instances

Before split, ODCR-1 shared with another AWS account

Figure 9: Before split, ODCR-1 shared with another AWS account
In this case, your options are more limited. ODCR-1 is shared with your partner’s AWS account, thus you can only split the unused capacity (maximum of two instances). After split, the newly created ODCR (ODCR-2) remains in your AWS account and isn’t shared with any other AWS account. This restriction helps prevent any disruption to your partner’s running workloads while still allowing for some flexibility in capacity management.

After split, ODCR-1 remains shared with another AWS account, and newly created ODCR-2 isn’t shared

Figure 10: After split, ODCR-1 remains shared with another AWS account, and newly created ODCR-2 isn’t shared

These scenarios demonstrate important factors about capacity management in both internal and partner-shared environments. You should carefully consider the sharing status of ODCRs before planning any splits or modifications, making sure of smooth operations for both your teams and your partners.

Special considerations for move capability

The move capability enables you to redistribute available (or excess) capacity between ODCRs. However, in certain cases, you can also use this capability to move used instances between ODCRs. This capability is particularly helpful if you want to merge partially used ODCRs into one for easier tracking and management. Along with the considerations for moving unused capacity, the following considerations apply for moving used capacity:

  1. Both source and destination ODCR are of open instance eligibility and in active state.
  2. The instances running inside the reservation are of open eligibility (in other words they are not targeting the reservation).
  3. Both source and destination ODCRs are owned by the same account.
  4. The source and destination ODCRs can be shared, but with the same list of accounts when moving used portion. This sharing to same accounts condition doesn’t apply to the unused portion of the ODCR.

When you specify the quantity of instances to be moved, by default any unused capacity is moved first, followed by any eligible running instances (the used capacity in your reservation).

In the next sections, we review where you can or can’t use this capability.

Scenario 1: source and destination ODCRs not shared with other account(s) (Team Transfers)

When managing capacity between your internal teams using the same AWS account (Account-A), you find the process clear. For example, when consolidating the ML team’s resources:

  • ODCR-1 (ML Team A): had ten capacities total (all with open eligibility), with eight in use and two unused.
  • ODCR-2 (ML Team B): had five capacities (all with open eligibility), all in use.

Before move, ODCR-1 and ODCR-2 both in the same AWS account, unshared

Figure 11: Before move, ODCR-1 and ODCR-2 both in the same AWS account, unshared

Both ODCRs belonged to the same account and weren’t shared externally, and the ODCRs have open instance eligibility. Therefore, you could freely move all ten instances from ODCR-1 to ODCR-2, creating a unified pool of 15 instances for the consolidated DevOps team.

After moving capacity from ODCR-1, ODCR-2 has combined total capacity of 15 with 2 unused

Figure 12: After moving capacity from ODCR-1, ODCR-2 has combined total capacity of 15 with 2 unused

Scenario 2: source and destination ODCRs shared with the same account(s) (External Partner Collaboration)

If your ML team (ODCR-1) collaborates with an external AI research partner (Account-B), your setup might look like the following:

  • ODCR-1: ten instances (eight used, two unused), all with open instance eligibility, shared with the research partner through AWS RAM.
  • ODCR-2: Five instances (all used), all with open instance eligibility, for internal Analytics team.

Before move, ODCR-1 and ODCR-2 both in the same AWS account, with ODCR-1 shared with other AWS account

Figure 13: Before move, ODCR-1 and ODCR-2 both in the same AWS account, with ODCR-1 shared with other AWS account

When your Analytics team needs more capacity, you can only move the two unused instances from ODCR-1 to ODCR-2, as the other eight are actively used in the partner collaboration.

Since ODCR-1 is shared with other AWS account, only unused capacity is moved to ODCR-2

Figure 14: Since ODCR-1 is shared with other AWS account, only unused capacity is moved to ODCR-2

Scenario 3: source and destination ODCRs shared with different account(s) (Multi-Partner Projects)

In this scenario involving managing capacity across different partner engagements:

  • ODCR-1: Ten instances (eight used, two unused), shared with a database partner (Account-B).
  • ODCR-2: Five instances (all used), shared with a security partner (Account-C).

ODCR-1 and ODCR-2 are shared with different AWS account

Figure 15: ODCR-1 and ODCR-2 are shared with different AWS account

Due to the different partner arrangements, in other words ODCRs shared with another accounts, you can only move the two unused capacities from ODCR-1 to ODCR-2. This makes sure that there is no disruption to database partner workloads.

Only unused capacity moved to ODCR-2 due to shared capacity reservations

Figure 16: Only unused capacity moved to ODCR-2 due to shared capacity reservations

These scenarios teach valuable lessons about capacity management in multi-account environments. You can develop a comprehensive sharing strategy that balances flexibility with partner commitments, enabling you to optimize your resource usage while maintaining strong partner relationships.

Conclusion

The new ODCR features of AWS –a split, move, and modify – represent a significant advancement in cloud capacity management. For your organization, these features transform how you handle compute resources, enabling more efficient operations and cost management. The ability to dynamically adjust and share Capacity Reservations provides the flexibility you need while maintaining the stability necessary for your critical workloads.

As cloud infrastructure continues to evolve, these features demonstrate the AWS commitment to addressing real-world challenges that you face when managing complex cloud environments. If you’re looking to optimize your AWS infrastructure, then these new ODCR capabilities offer powerful tools for better capacity management and resource usage.

To enhance your understanding of these capabilities, we’ve created a GitHub repository containing APIs for implementation purposes. For more details, refer to the updated Capacity Reservations documentation. If you have any questions or feedback, feel free to share them in the comments section or contact AWS Support.

Streamlining AMI creation with EC2 Image Builder components in AWS Marketplace

Post Syndicated from Art Baudo original https://aws.amazon.com/blogs/compute/streamliningamicreationwith-ec2imagebuilder/

This post is written by Smriti Ohri, Senior Product Manager, EC2 and Omar Chehab, Senior Product Manager, AWS Marketplace.

At re:Invent 2024, Amazon Web Services (AWS) announced the availability of third-party EC2 Image Builder components in AWS Marketplace. EC2 Image Builder is a fully managed service that streamlines the customization, testing, distribution, and lifecycle management of images. You can use this new feature to procure third-party components from AWS Marketplace directly on the EC2 Image Builder console and in the AWS Marketplace website. You can add multiple of these components to create your golden images.

A golden image is a customized and pre-configured Amazon Machine Image (AMI) needed for launching Amazon Elastic Compute Cloud (Amazon EC2) instances. It includes a standardized set of software, configurations, and security settings that meet an organization’s specific requirements, promoting consistency and efficiency across all EC2 instances.

EC2 Image Builder provides Amazon managed components, and you can build your own components that help when building custom images. However, you may need third-party software to build your golden images. Procuring this software can be time-consuming and necessitates custom setup. This integration aims to address these challenges by providing the ability to add third-party software from AWS Marketplace directly while creating golden images using EC2 Image Builder. While creating the image, you can customize your image recipe to use the latest version of components published in AWS Marketplace and make sure that you always remain up to date.

This post shows you how to find, subscribe to, and incorporate components from AWS Marketplace using the EC2 Image Builder console.

Prerequisites

You must have access to subscribe to a product in AWS Marketplace. Check AWS Marketplace subscription permissions.

Solution overview

Three high-level steps are involved in using the third-party component from AWS Marketplace in EC2 Image Builder:

  1. Discover and subscribe to the third-party component on the EC2 Image Builder console.
  2. Build the golden image with the third-party component.
  3. Launch the EC2 instance using the golden image.

Solution walkthrough: Streamlining AMI creation with EC2 Image builder components in AWS Marketplace

To perform the solution, go through the steps in the following sections.

Discover and subscribe to a component by Cribl

To discover and subscribe to the component, follow these steps:

  1. On the EC2 Image Builder console, in the navigation pane, choose Discover products. On the Components tab, you can view the list of available AWS Marketplace image products and the associated components. As shown in the following screenshot, choose View subscription options, which shows the different pricing offered.

 Figure 1: Discover components on EC2 Image Builder console

 Figure 1: Discover components on EC2 Image Builder console

  1. To subscribe to the product, from the dropdown menu choose the available offers and choose Subscribe, as shown in the following screenshot. You can now start using the associated component in your image recipe.

Figure 2: Subscribe to the product that has the component

Figure 2: Subscribe to the product that has the component

Build the golden image with the third-party component

To use the component, you can either subscribe to it first, or you can create the pipeline and subscribe to the component later based on your preference. For this walkthrough, I already subscribed to the component. The following section shows how to create a pipeline to build a custom AMI using the component to which I subscribed. You can follow a similar process to install other components to create your golden AMIs. The high-level steps are:

  1. Create the recipe.
  2. Create the pipeline.

To create the recipe, follow these steps:

  1. On the EC2 Image Builder console, choose Image recipes and Create image recipe. A recipe has a base image and the components that you want to install on it.

For this example, Amazon Linux was chosen as the base image operating system and “Amazon Linux 2023 x86” as the image name.

  1. In the Build components section, choose Add build components and, from the dropdown, choose AWS Marketplace. Search for the component to which you subscribed and choose Add to recipe, as shown in the following screenshot.

You can choose to use the latest version or a specific version of the component. For this walkthrough, the latest available version was selected.

Figure 3: Create recipe and add components from AWS Marketplace

Figure 3: Create recipe and add components from AWS Marketplace

To create the pipeline, an automation configuration (where you define the infrastructure configuration), image workflows, and distribution configuration, follow these steps:

  1. On the EC2 Image Builder console, choose Image pipelines and Create image pipeline. Provide the name of the pipeline and choose a Build schedule. You can also enable scanning, which scans your AMIs for Common Vulnerabilities and Exposures (CVEs) using Amazon Inspector.

For more information, refer to Amazon Inspector integration in Image Builder in the EC2 Image Builder User Guide. For this example, image scanning is enabled and the option to manually trigger the pipeline was selected.

Figure 4: Create the pipeline with the recipe and other configurations

Figure 4: Create the pipeline with the recipe and other configurations

  1. Choose the recipe you created with third-party components from AWS Marketplace.
  2. Choose the image workflows for the image creation process and define infrastructure configurations for creating the image.

You can choose Dedicated Host, Dedicated Instance, or Shared Tenancy. By default, it uses Shared Tenancy. For this example, the default configuration was selected. I chose the c5.large instance type since that is the supported instance type for this component.

Figure 5: Select the supported instance type in the infrastructure configurations

Figure 5: Select the supported instance type in the infrastructure configurations

  1. Provide the distribution configuration details to share or copy the output image to other accounts and in other AWS Regions.

To allow these accounts to use any component from AWS Marketplace, you must share license entitlements with these accounts using AWS License Manager. Instructions for sharing license entitlements are outside the scope of this post. To learn more, refer to Associating licenses with AMI based products using AWS License Manager.

  1. Choose the pipeline that you created and choose Run pipeline. After a while, the image is created and ready to use.

Run the EC2 instance using the golden image

Create an EC2 instance with the output golden image. You can also view the product code stamped on the AMIs, as shown in the following figure.


Figure 6: View the output image to check the product code

Conclusion

This feature helps you save time and automate the process of using the latest versions of the software. With this integration, you get a diverse set of software components from verified sellers in AWS Marketplace to address the monitoring, security, governance, and compliance needs of your organization. You can learn more about these components in the documentation. Visit AWS Marketplace to view all supported EC2 Image Builder components.

If you’re an AWS Partner, then you can publish your software as components in AWS Marketplace to cater to your customers. To learn more about onboarding your software to AWS Marketplace, visit this blog post. You can reach out to [email protected] if you have questions about this new feature or the publishing process.

Start building your custom AMIs using components from Marketplace today.