Tag Archives: AWS Trainium

Happy 20th Birthday, Amazon EC2

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/happy-20th-birthday-amazon-ec2/
Twenty years ago today, Jeff Barr wrote a blog post that launched the Amazon EC2 Beta. That single post introduced resizable Linux virtual servers in the cloud, billed by the hour, with one instance type (m1.small) in one Region (US East). It was minimal yet useful, and it changed how the world thinks about computing infrastructure.

In 2021, Jeff covered the fifteen years of EC2 with the backstory and memorable EC2 launches. Over the last five years, AWS has continued to push the boundaries of what cloud computing can deliver, building custom silicon for general-purpose and AI workloads and expanding EC2 into new form factors and deployment models that our customers in 2006 could not have imagined.

The 20 years in brief
In his 15th anniversary post, Jeff chose important milestones of EC2 that established the foundational building blocks that customers still rely on today. Amazon Elastic Block Store (2008) provided persistent block storage. Elastic Load Balancing, Auto Scaling, and Amazon CloudWatch (2009) made applications scalable and highly available. Amazon Virtual Private Cloud (2009) gave customers logically isolated networks. AWS Nitro System (2017) enabled faster innovation and enhanced security. AWS Graviton processors (2018) were designed for cost-sensitive scale-out workloads.

Over 20 years, EC2 grew from one to over 1,200 instance types to meet customer needs across general-purpose, compute-, memory-, and storage-optimized, accelerated computing, and high-performance computing families. These instances expanded from one AWS Region to 39 Regions globally. AWS also extended EC2 beyond the Region boundary with AWS Outposts (2018) running EC2 instances locally, AWS Local Zones (2019) place globally, and AWS Wavelength (2019) inside global 5G telecommunications carrier networks.
While I hate to play favorites, I want to choose some of my favorite EC2 launches of the past five years:

  • AWS Inferentia for ML inference at scale (2019): We introduced purpose-built ML inference instances (inf1) with AWS Inferentia chips. Amazon EC2 Inf2 instances became generally available in April 2023 for large-scale generative AI inference workloads. Together with the Inferentia family, AWS Trainium instances now give customers a full stack of AWS-designed silicon optimized for every phase of the AI lifecycle both inference and training.
  • EC2 Mac instances (2020): The first Mac instances (mac1) were built on Apple Mac mini with Intel Core i7 (Coffee Lake) on the AWS Nitro System. Mac M1 (mac2) instances launched in July 2022 as the first Arm-based macOS instances on EC2. M2 Pro Mac instances followed in 2023, M4 and M4 Pro Mac instances in 2025, M3 Ultra Mac instances and M4 Max Mac instances in 2026, giving Apple developers a complete range of cloud-based build and test environments for macOS, iOS, iPadOS, tvOS, watchOS, and visionOS apps.
  • AWS Trainium for full-stack AI workloads at scale (2021): In November 2021, we previewed Trn1 instances with AWS Trainium accelerators optimized for high-performance deep learning training. In December 2024, Trn2 instances powered by AWS Trainium2 launched, with Trn2 UltraServers linking 64 Trainium2 accelerators via NeuronLink for training trillion-parameter foundation models. At AWS re:Invent 2025, Trn3 UltraServers powered by AWS Trainium3 deliver the best token economics for next-generation agentic, reasoning, and video generation applications. A single Trn3 UltraServer interconnects up to 144 Trainium3 chips to train and serve the largest frontier models. Now, AWS Trainium3 delivers the leading price-performance for high-performance AI training and inference at scale.
  • EC2 Capacity Blocks for ML (2023): This new EC2 usage model further democratizes ML democratizes ML by making it easy to access GPU instances to train and deploy ML and generative AI models. You reserve the GPU capacity you need (initially P5 instances) for a future date and only for the duration you require. In November 2024, EC2 Capacity Blocks for ML added supported for provisioning in a matter of minutes and extending up to six months. Now, EC2 Capacity Blocks for ML supports P6-B300, P6-B200, P5e, P5en, P4d, P4de, Trn1, Trn2, and Trn3 instances in addition to P5.
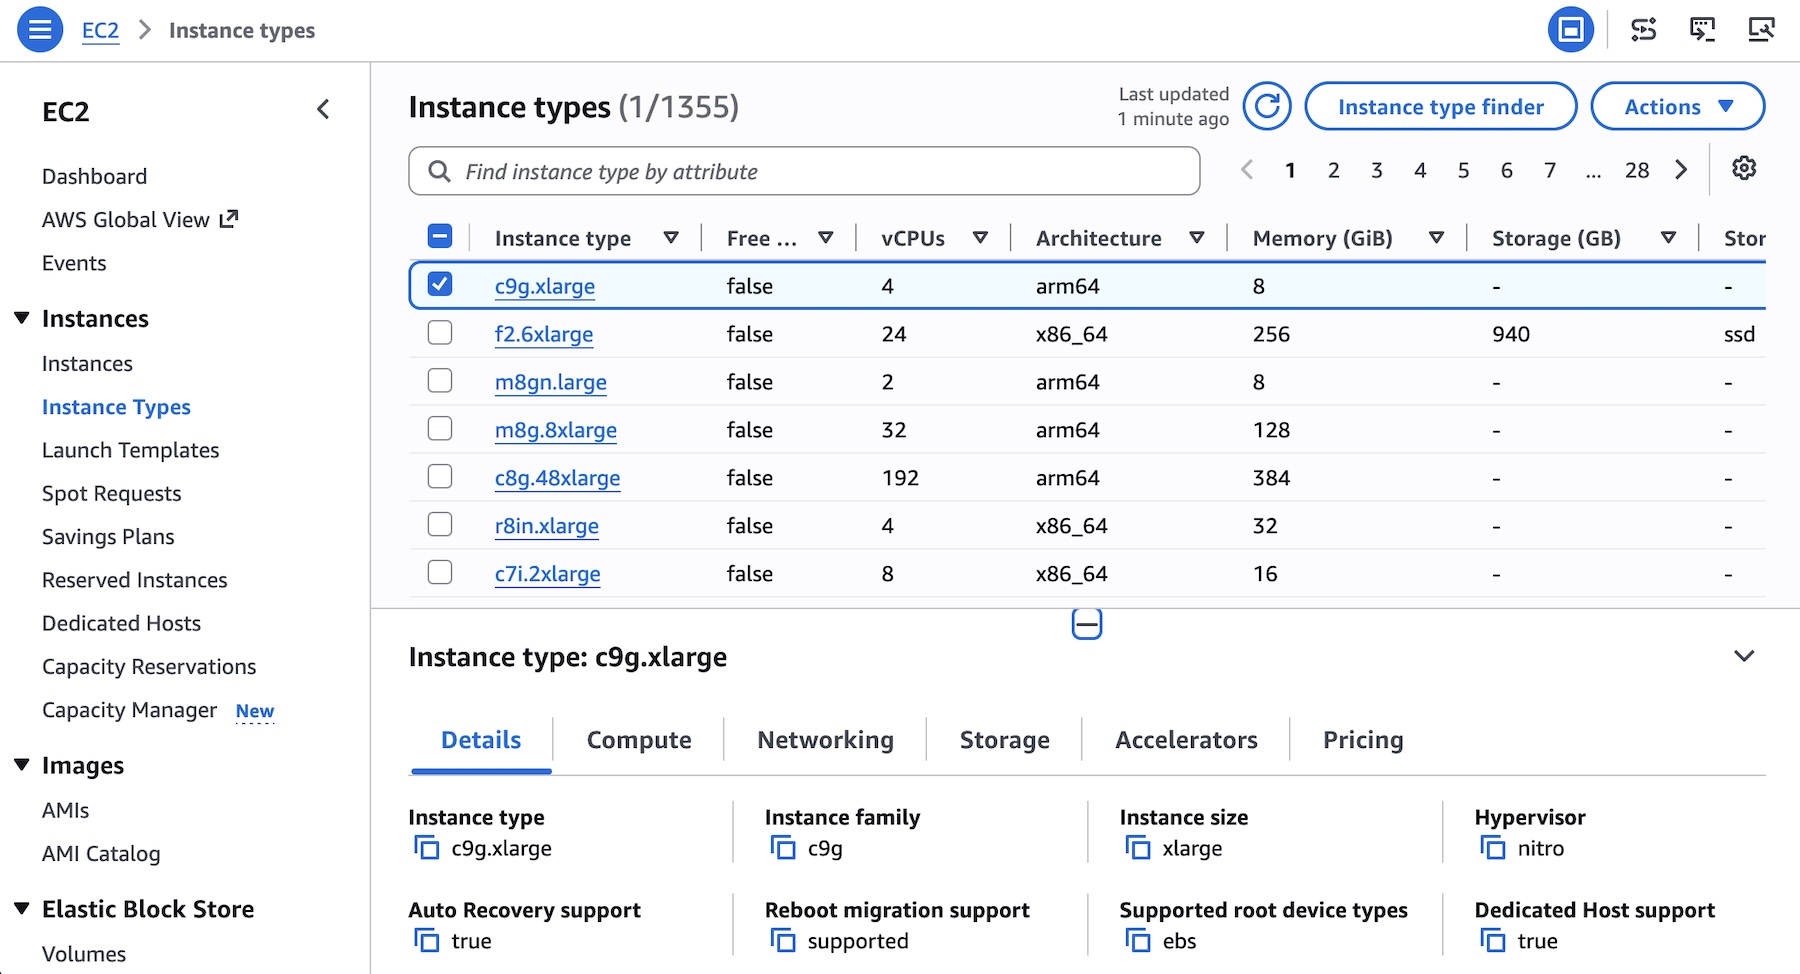
  • AWS Graviton5 (2025): Building on eight years of Graviton innovation since 2018, we previewed Graviton5 chips in AWS re:Invent 2025 and launched M9g and M9gd instances powered by Graviton5 and built on the sixth-generation AWS Nitro System. C9g and C9gd followed in June 2026. Now, Graviton5 features 192 cores, a 5x larger cache, and up to 33% lower inter-core latency, making it well suited for the growing demands of agentic AI workloads such as real-time reasoning, code generation, and multi-step task orchestration that require continuous, high-throughput CPU compute at scale.
  • AWS Nitro Isolation Engine (2026): Customers wanted to see, not just hear from us, proof of workload isolation in the Nitro Hypervisor. The Nitro Isolation Engine is a purpose-built component inside the Nitro Hypervisor, harnessing formal verification to provide mathematical assurance that customer workloads are isolated from each other and AWS operators, pioneering a new standard for mathematically proven cloud security. This feature is also based on the sixth-generation AWS Nitro System which has continued to evolve since our introduction in 2017.

The foundation underneath it all
Despite two decades of innovation, the fundamental value proposition of Amazon EC2 has not changed. Customers use it to get secure, resizable compute capacity in minutes, pay only for what they consume, and scale on demand without long-term commitments. That same flexibility now extends to AI workloads at a scale no one anticipated in 2006.

EC2 remains the foundational compute layer of AWS. Amazon ECS, Amazon EKS, AWS Lambda, AWS Fargate, AWS Batch, Amazon EMR, Amazon SageMaker AI, and Amazon Bedrock ultimately run on EC2 capacity. Every architectural pattern customers have built over the past twenty years, from simple web servers to trillion-parameter foundation model training clusters, starts with a decision to launch an instance.

We made strong foundational decisions in 2006, and we left room for the service to grow. Twenty years later, that strategy of creating services that are minimal-yet-useful, launching quickly, and iterating rapidly in response to your feedback continues to guide how we build. The next twenty years of cloud computing will demand capabilities we have not yet imagined. Amazon EC2 will continue to be the foundation where your workloads run.

To learn more about Amazon EC2, visit the Amazon EC2 product page or check out what’s new with EC2.

Channy

AWS Weekly Roundup: Strands Agents 1M+ downloads, Cloud Club Captain, AI Agent Hackathon, and more (September 15, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-strands-agents-1m-downloads-cloud-club-captain-ai-agent-hackathon-and-more-september-15-2025/

Last week, Strands Agents, AWS open source for agentic AI SDK just hit 1 million downloads and earned 3,000+ GitHub Stars less than 4 months since launching as a preview in May 2025. With Strands Agents, you can build production-ready, multi-agent AI systems in a few lines of code.

We’ve continuously improved features including support for multi-agent patterns, A2A protocol, and Amazon Bedrock AgentCore. You can use a collection of sample implementations to help you get started with building intelligent agents using Strands Agents. We always welcome your contribution and feedback to our project including bug reports, new features, corrections, or additional documentation.

Here is the latest research article of Amazon Science about the future of agentic AI and questions that scientists are asking about agent-to-agent communications, contextual understanding, common sense reasoning, and more. You can understand the technical topic of agentic AI with with relatable examples, including one about our personal behaviors about leaving doors open or closed, locked or unlocked.

Last week’s launches
Here are some launches that got my attention:

  • Amazon EC2 M4 and M4 Pro Mac instances – New M4 Mac instances offer up to 20% better application build performance compared to M2 Mac instances, while M4 Pro Mac instances deliver up to 15% better application build performance compared to M2 Pro Mac instances. These instances are ideal for building and testing applications for Apple platforms such as iOS, macOS, iPadOS, tvOS, watchOS, visionOS, and Safari.
  • LocalStack integration in Visual Studio Code (VS Code) – You can use LocalStack to locally emulate and test your serverless applications using the familiar VS Code interface without switching between tools or managing complex setup, thus simplifying your local serverless development process.
  • AWS Cloud Development Kit (AWS CDK) Refactor (Preview) –You can rename constructs, move resources between stacks, and reorganize CDK applications while preserving the state of deployed resources. By using AWS CloudFormation’s refactor capabilities with automated mapping computation, CDK Refactor eliminates the risk of unintended resource replacement during code restructuring.
  • AWS CloudTrail MCP Server – New AWS CloudTrail MCP server allows AI assistants to analyze API calls, track user activities, and perform advanced security analysis across your AWS environment through natural language interactions. You can explore more AWS MCP servers for working with AWS service resources.
  • Amazon CloudFront support for IPv6 origins – Your applications can send IPv6 traffic all the way to their origins, allowing them to meet their architectural and regulatory requirements for IPv6 adoption. End-to-end IPv6 support improves network performance for end users connecting over IPv6 networks, and also removes concerns for IPv4 address exhaustion for origin infrastructure.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Here are some additional news items that you might find interesting:

  • A city in the palm of your hand – Check out this interactive feature that explains how our AWS Trainium chip designers think like city planners, optimizing every nanometer to move data at near light speed.
  • Measuring the effectiveness of software development tools and practices – Read how Amazon developers that identified specific challenges before adopting AI tools cut costs by 15.9% year-over-year using our cost-to-serve-software framework (CTS-SW). They deployed more frequently and reduced manual interventions by 30.4% by focusing on the right problems first.
  • Become an AWS Cloud Club Captain – Join a growing network of student cloud enthusiasts by becoming an AWS Cloud Club Captain! As a Captain, you’ll get to organize events and building cloud communities while developing leadership skills. Application window is open September 1-28, 2025.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events as well as AWS re:Invent and AWS Summits:

  • AWS AI Agent Global Hackathon – This is your chance to dive deep into our powerful generative AI stack and create something truly awesome. From September 8 to October 20, you have the opportunity to create AI agents using AWS suite of AI services, competing for over $45,000 in prizes and exclusive go-to-market opportunities.
  • AWS Gen AI Lofts – You can learn AWS AI products and services with exclusive sessions and meet industry-leading experts, and have valuable networking opportunities with investors and peers. Register in your nearest city: Mexico City (September 30–October 2), Paris (October 7–21), London (Oct 13–21), and Tel Aviv (November 11–19).
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Aotearoa and Poland (September 18), South Africa (September 20), Bolivia (September 20), Portugal (September 27), Germany (October 7), and Hungary (October 16).

You can browse all upcoming AWS events and AWS startup events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Channy

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

Amazon EC2 Trn2 Instances and Trn2 UltraServers for AI/ML training and inference are now available

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/amazon-ec2-trn2-instances-and-trn2-ultraservers-for-aiml-training-and-inference-is-now-available/

The new Amazon Elastic Compute Cloud (Amazon EC2) Trn2 instances and Trn2 UltraServers are the most powerful EC2 compute options for ML training and inference. Powered by the second generation of AWS Trainium chips (AWS Trainium2), the Trn2 instances are 4x faster, offer 4x more memory bandwidth, and 3x more memory capacity than the first-generation Trn1 instances. Trn2 instances offer 30-40% better price performance than the current generation of GPU-based EC2 P5e and P5en instances.

In addition to the 16 Trainium2 chips, each Trn2 instance features 192 vCPUs, 2 TiB of memory, and 3.2 Tbps of Elastic Fabric Adapter (EFA) v3 network bandwidth, which offers up to 50% lower latency than the previous generation.

The Trn2 UltraServers, which are a completely new compute offering, feature 64x Trainium2 chips connected with a high-bandwidth, low-latency NeuronLink interconnect, for peak inference and training performance on frontier foundation models.

Tens of thousands of Trainium chips are already powering Amazon and AWS services. For example, over 80,000 AWS Inferentia and Trainium1 chips supported the Rufus shopping assistant on the most recent Prime Day. Trainium2 chips are already powering the latency-optimized versions of Llama 3.1 405B and Claude 3.5 Haiku models on Amazon Bedrock.

Up and Out and Up
Sustained growth in the size and complexity of the frontier models is enabled by innovative forms of compute power, assembled into equally innovative architectural forms. In simpler times we could talk about architecting for scalability in two ways: scaling up (using a bigger computer) and scaling out (using more computers). Today, when I look at the Trainium2 chip, the Trn2 instance, and the even larger compute offerings that I will talk about in a minute, it seems like both models apply, but at different levels of the overall hierarchy. Let’s review the Trn2 building blocks, starting at the NeuronCore and scaling to an UltraCluster:

NeuronCores are at the heart of the Trainium2 chip. Each third-generation NeuronCore includes a scalar engine (1 input to 1 output), a vector engine (multiple inputs to multiple outputs), a tensor engine (systolic array multiplication, convolution, and transposition), and a GPSIMD (general purpose single instruction multiple data) core.

Each Trainium2 chip is home to eight NeuronCores and 96 GiB of High Bandwidth Memory (HBM), and supports 2.9 TB/second of HBM bandwidth. The cores can be addressed and used individually, or pairs of physical cores can be grouped into a single logical core. A single Trainium2 chip delivers up to 1.3 petaflops of dense FP8 compute and up to 5.2 petaflops of sparse FP8 compute, and can drive 95% utilization of memory bandwidth thanks to automated reordering of the HBM queue.

Each Trn2 instance is, in turn, home to 16 Trainum2 chips. That’s a total of 128 NeuronCores, 1.5 TiB of HBM, and 46 TB/second of HBM bandwidth. Altogether this multiplies out to up to 20.8 petaflops of dense FP8 compute and up to 83.2 petaflops of sparse FP8 compute. The Trainium2 chips are connected across NeuronLink in a 2D torus for high bandwidth, low latency chip-to-chip communication at 1 GB/second.

An UltraServer is home to four Trn2 instances connected with low-latency, high-bandwidth NeuronLink. That’s 512 NeuronCores, 64 Trainium2 chips, 6 TiB of HBM, and 185 TB/second of HBM bandwidth. Doing the math, this results in up to 83 petaflops of dense FP compute and up to 332 petaflops of sparse FP8 compute. In addition to the 2D torus that connects NeuronCores within an instance, Cores at corresponding XY positions in each of the four instances are connected in a ring. For inference, UltraServers help deliver industry-leading response time to create the best real-time experiences. For training, UltraServers boost model training speed and efficiency with faster collective communication for model parallelism when compared to standalone instances. UltraServers are designed to support training and inference at the trillion parameter level and beyond; they are available in preview form and you can contact us to join the preview.

Trn2 instances and UltraServers are being deployed in EC2 UltraClusters to enable scale-out distributed training across tens of thousands of Trainium chips on a single petabit scale, non-blocking network, with access to Amazon FSx for Lustre high performance storage.

Using Trn2 Instances
Trn2 instances are available today for production use in the US East (Ohio) AWS Region and can be reserved by using Amazon EC2 Capacity Blocks for ML. You can reserve up to 64 instances for up to six months, with reservations accepted up to eight weeks in advance, with instant start times and the ability to extend your reservations if needed. To learn more, read Announcing Amazon EC2 Capacity Blocks for ML to reserve GPU capacity for your machine learning workloads.

On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.

If you used the AWS Neuron SDK to build your apps, you can bring them over and recompile them for use on Trn2 instances. This SDK integrates natively with JAX, PyTorch, and essential libraries like Hugging Face, PyTorch Lightning, and NeMo. Neuron includes out-of-the-box optimizations for distributed training and inference with the open source PyTorch libraries NxD Training and NxD Inference, while providing deep insights for profiling and debugging. Neuron also supports OpenXLA, including stable HLO and GSPMD, enabling PyTorch/XLA and JAX developers to utilize Neuron’s compiler optimizations for Trainium2.

Jeff;

Let’s Architect! Learn About Machine Learning on AWS

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-learn-about-machine-learning-on-aws/

A data-driven approach empowers businesses to make informed decisions based on accurate predictions and forecasts, leading to improved operational efficiency and resource optimization. Machine learning (ML) systems have the remarkable ability to continuously learn and adapt, improving their performance over time as they are exposed to more data. This self-learning capability ensures that organizations can stay ahead of the curve, responding dynamically to changing market conditions and customer preferences, ultimately driving innovation and enhancing competitiveness.

By leveraging the power of machine learning on AWS, businesses can unlock benefits that enhance efficiency, improve decision-making, and foster growth.

AWS re:Invent 2023 – Zero to machine learning: Jump-start your data-driven journey

In this session, see how organizations with constrained resources (budgets, skill gaps, time) can jump start their data-driven journey with advanced analytics and ML capabilities. Learn AWS Working Backwards best practices to drive forward data-related projects that address tangible business value. Then dive into AWS analytics and AI/ML capabilities that simplify and expedite data pipeline delivery and business value from ML workloads. Hear about low-code no-code (LCNC) AWS services within the context of a complete data pipeline architecture.

Take me to this video

See an architecture to analyze customer churn using AWS services

Figure 1. See an architecture to analyze customer churn using AWS services

Introduction to MLOps engineering on AWS

As artificial intelligence (AI) continues to revolutionize industries, the ability to operationalize and scale ML models has become a critical challenge. This session introduces the concept of MLOps, a discipline that builds upon and extends the widely adopted DevOps practices prevalent in software development. By applying MLOps principles, organizations can streamline the process of building, training, and deploying ML models, ensuring efficient and reliable model lifecycle management. By mastering MLOps, organizations can bridge the gap between AI development and operations, enabling them to unlock the full potential of their ML initiatives.

Take me to this video

MLOps maturity level will help to assess your organization and understand how to reach the next level.

Figure 2. MLOps maturity level will help to assess your organization and understand how to reach the next level.

Behind-the-scenes look at generative AI infrastructure at Amazon

To power generative AI applications while keeping costs under control, AWS designs and builds machine learning accelerators like AWS Trainium and AWS Inferentia. This session introduces purpose-built ML hardware for model training and inference, and shows how Amazon and AWS customers take advantage of those solutions to optimize costs and reduce latency.

You can learn from practical examples showing the impact of those solutions and explanations about how these chips work. ML accelerators are not only beneficial for generative AI workloads; they can also be applied to other use cases, including representation learning, recommender systems, or any scenario with deep neural network models.

Take me to this video

Discover the technology that powers our AI services

Figure 3. Discover the technology that powers our AI services

How our customers are implementing machine learning on AWS

The following resources drill down into the ML infrastructure that’s used to train large models at Pinterest and the experimentation framework built by Booking.com.

The Pinterest video discusses the strategy to create an ML development environment, orchestrate training jobs, ingest data into the training loop, and accelerate the training speed. You can also learn about the advantages derived from containers in the context of ML and how Pinterest decided to set up the entire ML lifecycle, including distributed model training.

The second resource covers how Booking.com accelerated the experimentation process by leveraging Amazon SageMaker for data analysis, model training, and online experimentation. This resulted in shorter development times for their ranking models and increased speed for the data science teams.

Take me to Pinterest video

Take me to Booking.com blog post

Let’s discover how Pinterest is using AWS services for machine learning workloads

Figure 4. Let’s discover how Pinterest is using AWS services for machine learning workloads

SageMaker Immersion Day

Amazon SageMaker Immersion Day helps customers and partners provide end-to-end understanding of building ML use cases. From feature engineering to understanding various built-in algorithms, with a focus on training, tuning, and deploying the ML model in a production-like scenario, this workshop guides you to bring your own model to perform lift-and-shift from on-premises to the Amazon SageMaker platform. It further demonstrates more advanced concepts like model debugging, model monitoring, and AutoML.

Take me to the workshop

Train, tune and deploy your workload using Amazon SageMaker

Figure 5. Train, tune and deploy your workload using Amazon SageMaker

See you next time!

Thanks for reading! With this post, introduced you to the art of possibility on using AWS machine learning services. In the next blog, we will talk about cloud migrations.

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.