Tag Archives: Configuration, compliance, and auditing

Quantum-resistant signing on AWS, Part 2: Enforce your ML-DSA algorithm policy with SCPs and IAM

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/security/quantum-resistant-signing-on-aws-part-2-enforce-your-ml-dsa-algorithm-policy-with-scps-and-iam/

You want to set a cryptographic algorithm policy and stop non-compliant choices from being made in your Amazon Web Services (AWS) environment. This post shows you how. As you adopt post-quantum cryptography, one of the first decisions you face is which algorithms and parameter sets fit your business needs, balancing security against signature size, key size, and performance. Your cloud environment’s job is to let you express that decision and enforce it consistently, so an approved choice stays fully usable while an excluded one cannot be introduced. This post works through one concrete example on AWS: taking an organization’s cryptographic algorithm policy and turning it into preventive and detective controls. The same patterns apply to whatever your approved set is today and whatever it becomes as standards evolve.

This post is Part 2 of a two-part series on quantum-resistant signing on AWS. Part 1, Build a software supply chain with ML-DSA, is for builders and constructs an end-to-end ML-DSA signing pipeline for binaries, container images, and software bills of materials. This part is for the security, governance, and compliance teams who decide which algorithms that pipeline, and everything else in the organization, is permitted to use, and who need that decision enforced.

AWS Key Management Service (AWS KMS) supports the ML-DSA digital signature scheme (FIPS 204) through three parameter sets, ML-DSA-44, ML-DSA-65, and ML-DSA-87, targeting NIST security categories 2, 3, and 5. All three are strong, standardized choices. Each one trades signature size, key size, and speed against security margin, the amount of cryptographic strength a parameter set holds in reserve above its target security category. ML-DSA-44 is the most compact and fastest. ML-DSA-65 and ML-DSA-87 carry a larger security margin, which is what you want for signatures that must stay trustworthy over a long lifetime.

Throughout this post, the examples use the same example policy: an organization that has standardized on ML-DSA-65 and ML-DSA-87 and wants ML-DSA-44 kept out of its approved set. That is a standardization decision, not a judgment that ML-DSA-44 is insecure (see the following note). Wherever you see ML-DSA-44 in the controls that follow, read it as the variant your policy doesn’t include; the mechanics are identical for any allow/deny split you choose. The approved set here is also the one the Part 1 architecture deploys: ML-DSA-87 for the root certificate authority (CA) and ML-DSA-65 for the subordinate CA and the code-signing key. Part 1 makes the choice; this post makes it stick.

Note: ML-DSA-44 is a valid choice. ML-DSA-44 is a fully NIST-standardized parameter set (FIPS 204) at NIST security category 2, which targets roughly 128-bit-class classical security (category 2 is benchmarked against the collision resistance of SHA-256). It produces the smallest signatures and public keys of the three variants (a 1312-byte public key and 2420-byte signature) and is the fastest to sign and verify, which makes it a strong fit for constrained devices, high-volume signing, and bandwidth- or storage-sensitive workloads. You would choose ML-DSA-65 or ML-DSA-87 instead to gain extra security margin for long-lived signatures or to align with an internal standard, not because ML-DSA-44 is weak.

What success looks like

The approved variants (ML-DSA-65 and ML-DSA-87 in the example) remain fully usable throughout. What you want to rule out is the introduction of a variant outside the policy (here, ML-DSA-44). Concretely, within the AWS service surfaces in scope, principals shouldn’t be able to:

  • Create ML-DSA-44 key material
  • Use existing ML-DSA-44 keys for signing or verification
  • Stand up private certificate authorities (CAs) that would introduce ML-DSA-44.

And any drift from those settings should be detected.

Scope and limitations

These controls operate on AWS service APIs, principally AWS KMS, AWS Private Certificate Authority (AWS Private CA), and AWS Certificate Manager (ACM). They don’t and can’t govern cryptography that runs on compute you control. For example, OpenSSL or an application might perform ML-DSA-44 signing on an Amazon Elastic Compute Cloud (Amazon EC2) instance, container, or AWS Lambda function. Protocol-level use, such as OpenSSH’s hybrid ssh-mldsa44-ed25519 public key authentication, is also outside the reach of Service control policies (SCPs) and AWS Identity and Access Management (IAM) and isn’t addressed in this post.

Certificate material brought in through acm:ImportCertificate or iam:UploadServerCertificate is also not algorithm-aware (see the Private CA section). Other TLS-terminating or signing services (for example Amazon CloudFront and Amazon API Gateway) and AWS IAM Roles Anywhere aren’t covered in this post and should be assessed separately. (Part 1 of this series uses IAM Roles Anywhere with ML-DSA certificates; controls for that service are out of scope here.)

These controls are intended to be applied as defense in depth. You can apply all of them or only a subset, depending on how prescriptive you want to be:

  • A blanket SCP at the organization root prevents member accounts from creating or using ML-DSA-44 keys. (SCPs don’t apply to the management account, so workloads there aren’t restricted.)
  • An SCP at a production organizational unit (OU) restricts keys only in production accounts.
  • If you need flexibility inside an account, use IAM permission boundaries instead of account-wide settings enforced through an SCP.

Choose the combination that matches your operating model. The policy examples here are written to apply across all AWS Regions. If you need to scope a control to specific Regions, add an aws:RequestedRegion condition.

The policies in this post are illustrative starting points. Authoring, validating, and maintaining the specific SCPs, IAM policies, and permission boundaries for your environment is your responsibility. Test all policies in a non-production environment before deployment and adjust example values (such as policy names and key Amazon Resource Names (ARNs)) to match your organization’s approved standards.

A note on cryptographic agility

Your algorithm policy isn’t fixed forever, and these controls shouldn’t be either. The point of expressing the policy as AWS controls is that you can revise it as your needs and the relevant standards change, tightening, loosening, or swapping the approved set without re-architecting. Treat the examples here as a template you adjust to whatever your current policy is.

A deny-based control that names specific algorithms is, in effect, an allow-list of everything it does not name. The risk is default-allow: any parameter set you have not explicitly denied is permitted, so a newly introduced variant, including one you have not yet evaluated, becomes usable until you notice it and add it to the deny list. Deprecation of an already-approved variant is easy to handle in this model, because you simply add the deprecated variant to the deny list. What the model does not catch on its own is the arrival of something new. Review these controls periodically and pair the deny-list with detection so a variant outside your policy surfaces quickly rather than waiting to be discovered.

The alternative is to write the condition against the approved set rather than the excluded one. A Deny that uses StringNotEquals with a list of approved key specs fires when the request’s key spec matches none of them, so a new or not-yet-evaluated variant is blocked by default until you add it. That closes the default-allow gap, at the cost of a policy update before anyone can use a newly approved variant. The family-level SCP in Part 1 of this series takes this shape: it denies creation of any signing key whose key spec isn’t ML_DSA_*. The examples in this post take the other shape and name the excluded variant, so that approved variants stay usable without a policy change. Both are valid. Choose based on whether you would rather block something new first and approve it later, or notice it first and decide then.

{
  "Sid": "OnlyApprovedMlDsaVariants",
  "Effect": "Deny",
  "Action": "kms:CreateKey",
  "Resource": "*",
  "Condition": {
    "StringLike": {
      "kms:KeySpec": "ML_DSA_*"
    },
    "StringNotEquals": {
      "kms:KeySpec": ["ML_DSA_65", "ML_DSA_87"]
    }
  }
}

The StringLike clause scopes the statement to ML-DSA key specs so it doesn’t affect other key types; the StringNotEquals clause denies any ML-DSA variant outside the approved list.

Just as algorithms and key sizes will be introduced over time, or move from approved to unapproved, so will AWS service operations. The set of operations through which an ML-DSA-44 key can be used today (AWS KMS Sign, Verify, and GetPublicKey) reflects current service capabilities and might expand as AWS releases new features. If your policy is to block use in addition to creation, you should periodically review the list of operations you restrict, because services evolve over time.

Background: Key spec compared to signing algorithm

AWS KMS support for ML-DSA introduces three key specs—ML_DSA_44, ML_DSA_65, and ML_DSA_87—that all use a single post-quantum signing algorithm: ML_DSA_SHAKE_256. This distinction drives which controls are effective.

  1. kms:KeySpec: Reflects the KeySpec property of the key. It’s evaluated both on CreateKey (the requested key spec) and on AWS KMS key resource operations that act on a specific key, including Sign, Verify, and GetPublicKey. This makes kms:KeySpec a reliable lever for both preventing creation of ML-DSA-44 keys and restricting use of existing ones, because it can single out ML_DSA_44 from ML_DSA_65 and ML_DSA_87.
  2. kms:SigningAlgorithm: Reflects the signing algorithm supplied on Sign and Verify, which is ML_DSA_SHAKE_256 for all three variants. It therefore can’t distinguish ML-DSA-44 from the approved variants and shouldn’t be used for this purpose.

The practical consequence: for keys held in AWS KMS, preventing ML-DSA-44 key material from being created is the most robust single control. If no ML-DSA-44 KMS keys exist, none can be used for signing through AWS KMS and none can become the subject key of a certificate. CA keys and TLS server keys are separate material: AWS Private CA generates and holds a CA’s key pair in its own HSMs, and ACM-issued, imported, or uploaded TLS certificates carry their own keys, so those surfaces are governed by the AWS Private CA and certificate controls later in this post. Where ML-DSA-44 KMS keys already exist, their use can additionally be restricted with kms:KeySpec.

Organization and account-level blocking using SCPs

SCPs can be applied at the organization root or to a specific OU to restrict ML-DSA-44. Placement determines the effective scope: it applies organization-wide when attached at the root; attached to an OU, it applies to the accounts within that OU. An SCP is the broadest-scope preventive control available.

Note that SCPs apply to member accounts and OUs but not to the organization’s management account, so avoid running ML-DSA-44-capable workloads in the management account, where an SCP will not restrict them.

The following example SCP denies both the creation of ML-DSA-44 keys (kms:CreateKey) and their use (kms:Sign, kms:Verify, kms:GetPublicKey), matching on the ML_DSA_44 key spec in each case. The creation deny stops new keys from being created; the usage deny covers keys that already exist, whether created before the SCP was attached or living in an account that later joins the OU, because kms:KeySpec is also evaluated at request time on those usage operations.SCPs are guardrails: a Deny in an SCP can’t be overridden by any IAM policy within member accounts.

Attach the following SCP at the organization root (or relevant OU):

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyMLDSA44KeyCreation",
      "Effect": "Deny",
      "Action": "kms:CreateKey",
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "kms:KeySpec": "ML_DSA_44"
        }
      }
    },
    {
      "Sid": "DenyMLDSA44KeyUsage",
      "Effect": "Deny",
      "Action": [
        "kms:Sign",
        "kms:Verify",
        "kms:GetPublicKey"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "kms:KeySpec": "ML_DSA_44"
        }
      }
    }
  ]
}

Scope the usage deny to the three key-spec-aware actions. Limit the use of Deny to kms:Sign, kms:Verify, and kms:GetPublicKey (testing confirmed kms:KeySpec is evaluated on all three). Avoid a blanket kms:*: a wildcard that would also catch management operations such as DescribeKey, DisableKey, and ScheduleKeyDeletion, which you need to inspect or clean up those same keys, effectively locking you out of managing the keys you’re trying to remove. If you use multi-Region keys, also add kms:ReplicateKey to the creation deny: replicating an ML-DSA-44 primary key creates a new ML-DSA-44 key in another Region, and kms:KeySpec is evaluated on ReplicateKey as well.

Combining with a family-level guardrail. This SCP governs which ML-DSA parameter set is allowed; it says nothing about RSA or ECDSA. Part 1 of this series includes a complementary SCP that denies creation of any signing key whose key spec isn’t ML-DSA. Attached together, they require every new signing key to be ML-DSA and to be an approved variant.

Operational considerations. A blanket Deny at the organization root is the strongest control but has trade-offs: it removes any ability to create ML-DSA-44 keys anywhere in scope, with no exception path, which can block legitimate testing and might cause infrastructure as code (IaC) or pipeline runs that attempt ML-DSA-44 creation to fail. To preserve flexibility, consider scoping the Deny to a production OU and using IAM permission boundaries (see the following section) in build and non-production accounts.

What the caller sees. When an SCP denies a request, the caller receives an AccessDenied error indicating an explicit deny in a service control policy. For same-account and same-organization requests, the error includes the type of the denying policy and, as the enhanced error messages roll out across services, its ARN. The error doesn’t expose the SCP policy contents, and the user being blocked often can’t see the SCPs applied to their environment. Document the SCP ARN and its purpose internally so support teams can map an AccessDenied quickly.

Prevent ML-DSA-44 key creation in AWS KMS (principal-level)

The following IAM policy blocks ML-DSA-44 at the principal level. It is the identity-based counterpart to the SCP shown earlier, useful when you want per-account or per-role control rather than an organization-wide guardrail. Attach it to the IAM role or user you want to constrain.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyMLDSA44KeyCreation",
      "Effect": "Deny",
      "Action": "kms:CreateKey",
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "kms:KeySpec": "ML_DSA_44"
        }
      }
    }
  ]
}

Key points:

  1. The condition value is ML_DSA_44 (underscores, not hyphens).
  2. This policy blocks CreateKey only. To also block use of existing ML-DSA-44 keys at the principal level, add the Sign, Verify, and GetPublicKey deny shown in the Restricting use of existing ML-DSA-44 keys section.
  3. For comprehensive, non-overridable coverage, deploy as an SCP rather than relying solely on principal-level policies.

IAM permission boundaries

IAM permission boundaries set the maximum permissions an identity-based policy can grant to an IAM role or user and can be used as an alternative or complement to using SCPs. The effective permissions are the intersection of the identity-based policy and the boundary, and a Deny in a boundary can’t be overridden by an attached policy. Boundaries are useful where you want per-account or per-role flexibility (for example, in build or non-production accounts) rather than a blanket, multi-account deny.

Operational consideration. A permission boundary only takes effect on principals that have it attached. To rely on boundaries as a control, you need a mechanism to enforce the boundary on all IAM principals programmatically. One example enforcement mechanism would be an SCP that denies iam:CreateRole, iam:CreateUser, iam:PutRolePermissionsBoundary, and iam:PutUserPermissionsBoundary unless the approved boundary is set (using the iam:PermissionsBoundary condition key), and denies iam:DeleteRolePermissionsBoundary and iam:DeleteUserPermissionsBoundary outright so the boundary can’t be removed after the fact. You would also want to probe for non-conforming principals periodically and respond, perhaps by automatically attaching the PermissionsBoundary. IAM users shouldn’t be used, but the enforcement should account for the possibility that they exist.

Because a boundary only sets a ceiling and does not itself grant anything, it opens with Allow on all actions, then denies ML-DSA-44 key creation specifically. The following permission boundary denies creation of ML-DSA-44 keys:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowAll",
      "Effect": "Allow",
      "Action": "*",
      "Resource": "*"
    },
    {
      "Sid": "DenyMLDSA44KeyCreation",
      "Effect": "Deny",
      "Action": "kms:CreateKey",
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "kms:KeySpec": "ML_DSA_44"
        }
      }
    }
  ]
}

To also block use of existing ML-DSA-44 keys for the principals carrying this boundary, add the Sign, Verify, and GetPublicKey deny statement shown in the following section (which also uses kms:KeySpec).

Restricting use of existing ML-DSA-44 keys

As described in the Background section, kms:KeySpec is also evaluated on Sign, Verify, and GetPublicKey, reflecting the KeySpec of the key being used. You can therefore deny those operations when kms:KeySpec equals ML_DSA_44 while continuing to permit ML_DSA_65 and ML_DSA_87. The IAM policy below, attached to an IAM principal, does exactly that.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyMLDSA44KeyUsage",
      "Effect": "Deny",
      "Action": [
        "kms:Sign",
        "kms:Verify",
        "kms:GetPublicKey"
      ],
      "Resource": "*",
      "Condition": {
        "StringEquals": {
          "kms:KeySpec": "ML_DSA_44"
        }
      }
    }
  ]
}

This deny can also live in an AWS KMS key policy. The same kms:KeySpec deny can be placed directly in the key policy of an AWS KMS key. A key policy is a resource policy, so the statement must include a Principal element. Identity policies and SCPs do not name principals to which they apply. A deny in the key policy is a resource-side backstop that protects a specific key, while an SCP gives non-overridable organization-wide coverage. To turn the previous example into an AWS KMS key policy, add a Principal element to the statement (for example "Principal": {"AWS": "*"}, or a more specific principal), and keep the rest of it the same.

Additional approaches

Depending on your goals you might also want to remove the key material itself rather than only deny its use. Remember that it is difficult to know what data has been signed by a specific key, unless you track that somehow. Deleting a key that was used will make signature verification impossible. Take great care to make sure keys are not used before deleting them.

  1. Disable or schedule deletion of the keys. Disabling stops key use immediately and is reversible. Key deletion is definitive but irreversible after the waiting period, so confirm before scheduling.
  2. Deny Sign, Verify, and GetPublicKey by specific key ARN. You can target named keys rather than the whole key spec. To do this, you would list the exact key ARNs in the Resource element of the IAM policy (no condition key required). This is effective for targeting a single key specifically, but it is difficult to maintain lists of key ARNs. Use this strategy sparingly. If you’re considering using an IAM policy naming a key ARN, remember that a Deny in the key policy of the target key accomplishes the same goal and is attached to the key itself.
  3. Finding existing keys (only needed if you disable or delete). A Deny in an IAM policy or SCP, based on kms:KeySpec, doesn’t require you to know which keys exist – it applies by key spec at request time. If you want to disable or delete existing ML-DSA-44 keys, you need to locate them. AWS KMS has no server-side filter for key spec, so you must enumerate keys with ListKeys and call DescribeKey and inspect each KeySpec. This client-side filtering pattern is common across AWS APIs and is well supported by pagination in the AWS SDKs. You can also use AWS Config to record and query KMS key resources.

Reference: Choosing a KMS key spec – kms:KeySpec condition key

Approved ML-DSA variants and control of AWS Private CA

AWS Private CA sets a certificate authority’s (CA’s) signing algorithm at creation time, in the CertificateAuthorityConfiguration parameter of CreateCertificateAuthority (valid values include ML_DSA_44, ML_DSA_65, and ML_DSA_87). There is currently no condition key for the algorithm, so an SCP cannot enforce signing algorithm. The approach in this section controls who can create CAs and pins the algorithm in that trusted path, backed by AWS CloudTrail-based detection.

Recommended approach

  1. Restrict who can create CAs. Deny acm-pca:CreateCertificateAuthority broadly via SCP, and allow it only for a small set of trusted roles or an approved provisioning pipeline. This removes the ability for arbitrary principals to stand up a CA with an unapproved algorithm.
  2. Pin the algorithm in the trusted path. Have that approved pipeline or infrastructure-as-code template hard-code SigningAlgorithm to ML_DSA_65 or ML_DSA_87 in CertificateAuthorityConfiguration. Because AWS Private CA exposes no algorithm condition key, this provisioning path is the enforcement point. Note that the CA’s algorithm pins the signature on the certificates it issues; the subject key in each certificate comes from the CSR, which AWS Private CA copies without validating its algorithm, so pin the CSR key algorithm in the same issuance pipeline.
  3. Control the trust chain. On the PKI side, only add approved CAs to your trust stores and issuance hierarchies, and do not trust or subordinate CAs that could issue ML-DSA-44. This prevents an unapproved CA from being introduced into a trusted path.
  4. Detect drift. Use CloudTrail to capture CreateCertificateAuthority calls and AWS Config to flag any CA whose configuration uses ML_DSA_44, so an unapproved CA is caught quickly.

Part 1 of this series shows what this looks like in practice: it creates an ML-DSA-87 root CA and an ML-DSA-65 subordinate CA with CreateCertificateAuthority, activates them, and distributes the resulting chain to verifiers. In the model described here, those are the calls that only your approved provisioning pipeline is allowed to make.

Setting the ML-DSA value in CertificateAuthorityConfiguration. The same variant goes in both the KeyAlgorithm and SigningAlgorithm fields (for example, KeyAlgorithm=ML_DSA_65 with SigningAlgorithm=ML_DSA_65). Note a difference in signing algorithms between AWS KMS and AWS Private CA. With AWS Private CA, the SigningAlgorithm takes the variant value directly (ML_DSA_44, ML_DSA_65, and ML_DSA_87), and doesn’t accept ML_DSA_SHAKE_256. In contrast, AWS KMS uses ML_DSA_SHAKE_256 as its signing algorithm. Be aware that some older AWS Command Line Interface (AWS CLI) builds omitted descriptions of the ML-DSA variants from the built-in CLI help, so don’t rely on the help in the AWS CLI to determine valid values. For more information, see CertificateAuthorityConfiguration API Reference.

Known limitation. Some surfaces have no algorithm condition key, so you enforce them through provisioning and detection rather than policy. acm-pca:CreateCertificateAuthority has no condition key for the algorithm, and acm:ImportCertificate and iam:UploadServerCertificate are not algorithm-aware, so a disallowed signature setting on a created, imported, or uploaded certificate cannot be blocked by an IAM policy or SCP condition. Govern these through your provisioning process, restrict who can call them, and deny the import and upload actions entirely where they are not required. The controls above remain the available mitigation.

In particular, iam:UploadServerCertificate doesn’t support any method to prevent use of particular algorithms, and AWS doesn’t recommend using this API to generate and upload certificates. This API predates ACM and exists mainly to cover AWS Regions or partitions where ACM is not yet available. While a new Region or partition is being built out, workloads can still need a TLS server certificate before ACM support has shipped there, and uploading a certificate to IAM gives you a place to store and reference it in the meantime. Once ACM is available in that Region, you should use ACM instead. Outside that narrow case, deny iam:UploadServerCertificate unless it is genuinely required.

ACM-issued leaf certificates. A CA’s own key and signing algorithm are separate from the leaf certificates that ACM issues from it. If you use ACM to request leaf certificates, you can constrain the leaf’s key algorithm with the acm:KeyAlgorithm condition key on acm:RequestCertificate. This lets you allow-list approved algorithms for leaf certificates using SCPs or IAM policies, similar to the AWS KMS examples earlier in this post. Be aware that, at the time of writing, ACM doesn’t offer ML-DSA leaf certificates. So a policy like this is a forward-looking defense-in-depth control rather than an immediate ML-DSA-44 risk. The IAM example below is illustrative (using example approved algorithms). Since this is an evolving part of the service, be sure to validate this in your environment before relying on it.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RestrictACMLeafKeyAlgorithm",
      "Effect": "Deny",
      "Action": "acm:RequestCertificate",
      "Resource": "*",
      "Condition": {
        "StringNotEqualsIfExists": {
          "acm:KeyAlgorithm": [
            "EC_secp384r1",
            "RSA_2048"
          ]
        }
      }
    }
  ]
}

This example uses StringNotEqualsIfExists so it denies only requests that specify a disallowed algorithm. With plain StringNotEquals, a request that omits acm:KeyAlgorithm would also be denied, because the missing key makes the condition evaluate true. Choose the operator that matches whether you want to block requests that leave the algorithm unspecified.

Prevent ML-DSA-44 usage in TLS for NLB and ALB

Elastic Load Balancing, for both network load balancers (NLB) and application load balancers (ALB), terminates TLS on behalf of your applications. The certificates used by these listeners are requested through or imported into ACM, or uploaded to IAM. A listener’s configured security policy and its certificate determine what’s offered during negotiation. At the time of writing, ACM requests and imports accept RSA and ECDSA keys only, and NLB and ALB listeners accept RSA and ECDSA certificates only, so no ML-DSA certificate can be bound to a listener today. As with the ACM leaf-certificate policy earlier, the controls in this section are forward-looking defense in depth rather than a mitigation of an immediate ML-DSA-44 risk.

Certificate controls (the effective mechanism for ML-DSA-44)

Because the listener API calls reference a certificate only by ARN, you can’t write an SCP on CreateListener, ModifyListener, or AddListenerCertificates that inspects the certificate’s algorithm. IAM conditions can’t reference attributes of a separately-referenced resource. Keeping ML-DSA-44 out of TLS therefore relies on there being no ML-DSA-44 certificate material to associate:

  1. Configure your private CA to issue only ML_DSA_65 or ML_DSA_87 certificates, and control who can create CAs.
  2. Prevent ML-DSA-44 key creation in AWS KMS, so that no KMS-held ML-DSA-44 key can become the subject key of a certificate. TLS server keys for ACM-issued, imported, or uploaded certificates are not KMS keys; those are governed by items 1 and 3.
  3. Control imported and uploaded certificates through your provisioning process or deny the import and upload actions where not required, as described in the AWS Private CA section.

Detective controls

CloudTrail records the certificate and listener API calls in this section: certificate creation and import (acm-pca:CreateCertificateAuthority, acm:ImportCertificate, iam:UploadServerCertificate) and listener configuration (CreateListener, ModifyListener, AddListenerCertificates). Whether the algorithm shows up in the event depends on what the call itself carries. Creation calls that take the algorithm as an input record it: kms:CreateKey logs the KeySpec, and acm-pca:CreateCertificateAuthority logs the signing algorithm. That makes CloudTrail effective for catching the creation of ML-DSA-44 key material or a CA. A listener binding references its certificate only by ARN, so the certificate’s algorithm does not appear in that event. To evaluate the algorithm of a bound or imported certificate, use AWS Config resource evaluation as the detective backstop.

Summary for TLS

The primary preventive control is the certificate material itself: with no ML-DSA-44 CA, no ML-DSA-44 KMS key, and certificate import and upload controlled, no ML-DSA-44 certificate can be issued or bound. Where you also operate an allow-list of permitted TLS security policies, the elasticloadbalancing:SecurityPolicy condition key (on CreateListener and ModifyListener) can additionally constrain which TLS policies listeners can use.

Summary of controls

The following table maps the example policy (allow ML-DSA-65 or ML-DSA-87, exclude ML-DSA-44) to the available controls. Modify the controls to limit use to the approved set of algorithms your policies require.

Area Control Status
Block ML-DSA-44 key creation (Organization-wide or for all accounts in an organization OU) SCP on kms:CreateKey using kms:KeySpec Fully supported via condition key
Block ML-DSA-44 key creation (per account or per role) IAM policy or permission boundary using kms:KeySpec Supported; requires programmatic enforcement of boundaries
Block use of existing ML-DSA-44 keys Deny Sign, Verify, and GetPublicKey using kms:KeySpec (key policy, IAM, or SCP); optionally disable and delete keys Supported using kms:KeySpec (not kms:SigningAlgorithm)
Only allow approved variants in Private CA Restrict who can create CAs; pin ML_DSA_65 or ML_DSA_87 in provisioning path No algorithm condition key; enforce using process and detection
Limit variants in imported or uploaded TLS certificates Process controls, or deny import or upload APIs (prefer ACM over iam:UploadServerCertificate) APIs aren’t algorithm-aware
Block use of ML-DSA-44 in TLS with network load balancers (NLB) and application load balancers (ALB) Restrict TLS policy using elasticloadbalancing:SecurityPolicy; control cert material TLS-policy restriction supported; no per-cert algorithm condition
Detect use of unapproved variants CloudTrail (API-level) and AWS Config custom rules Supported using custom AWS Config rules; not managed rules

Conclusion

In this post, you learned how to use ML-DSA as an example of turning a cryptographic algorithm policy into enforceable AWS controls. The key lever is the kms:KeySpec condition key: it keeps your approved parameter sets (ML-DSA-65 and ML-DSA-87) fully usable while preventing the creation and use of a parameter set you’ve excluded (ML-DSA-44) on the CreateKey, in addition to the Sign, Verify, and GetPublicKey operations, where kms:SigningAlgorithm can’t tell the variants apart. Applied as defense in depth across SCPs, IAM policies, permission boundaries, and KMS key policies, and extended to the surfaces that have no algorithm condition key (AWS Private CA, certificate import, and Elastic Load Balancing TLS) through provisioning controls plus AWS CloudTrail and AWS Config drift detection, these controls give you a consistent way to keep an unapproved variant out of your accounts.

The pattern isn’t specific to ML-DSA-44. Because your algorithm policy will change as standards and your own requirements evolve, treat these controls as a reusable template and re-point the same condition keys and guardrails at whatever your approved set becomes. This adaptability is the practical meaning of cryptographic agility: changing what you allow without re-engineering how you enforce it.

To get started, review ML-DSA keys in AWS KMS and Choosing a KMS key spec, and test the example policies in a non-production environment before you deploy them.

To see the workloads these controls govern, read Part 1 of this series, which builds a complete ML-DSA signing pipeline, from key creation and PKI through artifact signing and verification, using the approved set enforced here.

Resources

If you have feedback about this post, submit comments in the Comments section below.

Harshvardhan Chunawala

Harshvardhan Chunawala

Harshvardhan is a Solutions Architect and Security SME at AWS, where he leads cross-team efforts with Amazon Leo, Amazon Security, and AWS Agentic AI. A Golden Jacket awardee with over a decade in cloud security, he’s an advisory board member, Visiting Faculty, and researcher at Carnegie Mellon University. He advises C-suite executives, enterprise leaders, and startup founders worldwide on building secure, scalable cloud platforms.

Blake Roberts

Blake Roberts

Blake Roberts is a Sr. Solutions Architect at AWS and a member of the AWS Security Technical Field Community. He helps UK public sector customers navigate the security challenges and questions they face, covering post-quantum cryptography, threat detection and incident response, governance at a strategic scale, and more. Prior to joining AWS, Blake served in the British Army for 9 years. Blake is an avid reader and keen runner.

Quantum-resistant signing on AWS, Part 1: Build a software supply chain with ML-DSA

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/security/quantum-resistant-signing-on-aws-part-1-build-a-software-supply-chain-with-ml-dsa/

Software supply chain attacks have grown in both frequency and sophistication. Recent high-profile compromises of build systems and open source dependencies demonstrate that attackers increasingly target the trust mechanisms that verify software integrity. Those trust mechanisms rely on digital signature algorithms, and today many use traditional algorithms such as Rivest-Shamir-Adleman (RSA) and the Elliptic Curve Digital Signature Algorithm (ECDSA). If a sufficiently powerful quantum computer could forge these signatures, an attacker could potentially inject unauthorized code into signed artifacts, fabricate build attestations, or impersonate legitimate publishers. Using quantum-resistant signatures today defends against threats that might emerge in the future.

Since 2025, the Commercial National Security Algorithm Suite 2.0 (CNSA 2.0), published by the US National Security Agency (NSA), has required US National Security Systems (NSS) to “support and prefer” quantum-resistant signatures for software and firmware, with exclusive use mandated by 2030. The EU Cyber Resilience Act (CRA) takes full effect in December 2027. It requires manufacturers to maintain verifiable software integrity throughout a product’s lifecycle. Organizations that ship software to US federal agencies or sell products in the European market face converging deadlines that demand action now.

Amazon Web Services (AWS) provides the building blocks to construct a quantum-resistant software supply chain today using production-ready, generally available services. In this post, I show you how to combine Module-Lattice-Based Digital Signature Algorithm (ML-DSA) keys in AWS Key Management Service (AWS KMS), ML-DSA certificate hierarchies in AWS Private Certificate Authority, and ML-DSA trust anchors in AWS Identity and Access Management (IAM) Roles Anywhere into an end-to-end signing architecture for binaries, container images, and software bills of materials (SBOMs).

This post is Part 1 of a two-part series on adopting ML-DSA signatures, standardized in NIST FIPS 204 (ML-DSA) signatures, on AWS. As of Oct 2026, this series is the first end-to-end guide from any cloud provider for post-quantum signing across the software supply chain, from establishing an ML-DSA root of trust to enforcing algorithm policy across an organization. This part is for builders and walks through constructing and operating the signing pipeline. Part 2, Enforce your ML-DSA algorithm policy with SCPs and IAM, is for security and governance teams and shows how to turn the algorithm choices made here into preventive and detective controls across an organization.

Understanding the harvest now, forge later threat

After a cryptographically relevant quantum computer (CRQC) exists, the mathematical problems protecting today’s public-key cryptography can be solved efficiently. Attacks that are impractical today because of the computational complexity suddenly become practical using a CRQC. Most discussions of post-quantum cryptography (PQC) focus on the harvest now, decrypt later threat to data confidentiality. The asymmetric keys protecting data in transit can be efficiently derived using a CRQC, exposing the data that was meant to be protected. Digital signatures rely on the same asymmetric mathematical problems that a CRQC would break. This means that software supply chains face a parallel threat that targets integrity rather than confidentiality. An attacker who records signed artifacts today can forge those signatures in the future on a totally different artifact, using a CRQC.

Consider firmware signed with ECDSA P-256 and deployed to a fleet of embedded devices in 2026. These devices verify the firmware signature on every boot for their 15-year operational lifetime and can’t be recalled to re-sign after deployment. If a CRQC becomes operational in 2035, an attacker could produce a valid-looking signature over tampered firmware, and every device in the fleet would accept it as authentic on next restart. For organizations that rely on classical digital signatures as the primary mechanism for verifying software integrity, this weakens a critical link in the verification chain. This is why CNSA 2.0 specifies aggressive timelines for digital signatures: the artifacts you sign today must remain trustworthy for their full operational lifetime.

ML-DSA is designed to resist attacks from both classical and quantum computers. AWS KMS, AWS Private CA, and AWS IAM Roles Anywhere all support ML-DSA, making it possible to address the forge-later threat across your supply chain today without additional tooling.

Architecture overview: Five pillars of a quantum-resistant supply chain

The architecture comprises five trust pillars that together protect your software delivery pipeline:

  1. ML-DSA key management in AWS KMS – All signing keys are generated and protected in FIPS 140-3 Security Level 3 hardware security modules (HSMs). Private keys never leave the HSM boundary.
  2. ML-DSA public key infrastructure (PKI) through AWS Private CA – A certificate hierarchy (root CA, subordinate CA, end-entity certificates) binds ML-DSA public keys to identities, establishing who signed what. CA private keys are generated and stored in hardware-protected HSMs managed by the service and never leave the HSM boundary.
  3. Quantum-resistant workload identity (for external build agents) – For continuous integration and delivery (CI/CD) agents running outside AWS that authenticate through X.509 certificates, IAM Roles Anywhere with ML-DSA certificates ties the signer’s identity back to the same quantum-resistant root of trust.
  4. ML-DSA artifact signing – Build outputs (binaries, container image manifests, packages) are signed using AWS KMS ML-DSA keys. Signatures are stored alongside artifacts in Amazon Simple Storage Service (Amazon S3) or Amazon Elastic Container Registry (Amazon ECR).
  5. ML-DSA SBOM integrity attestation – The SBOM for each release is wrapped in an in-toto Statement that names the artifact it describes by digest, and the Statement is signed with the same ML-DSA code-signing key. This provides quantum-resistant proof that the dependency manifest hasn’t been tampered with and that it belongs to the artifact it accompanies.

These pillars create a chain of trust: AWS Private CA protects the root CA key in its own HSMs, issues certificates that bind identities to AWS KMS code-signing keys, IAM Roles Anywhere uses those certificates to authenticate build agents, and authenticated agents sign every artifact and SBOM they produce.

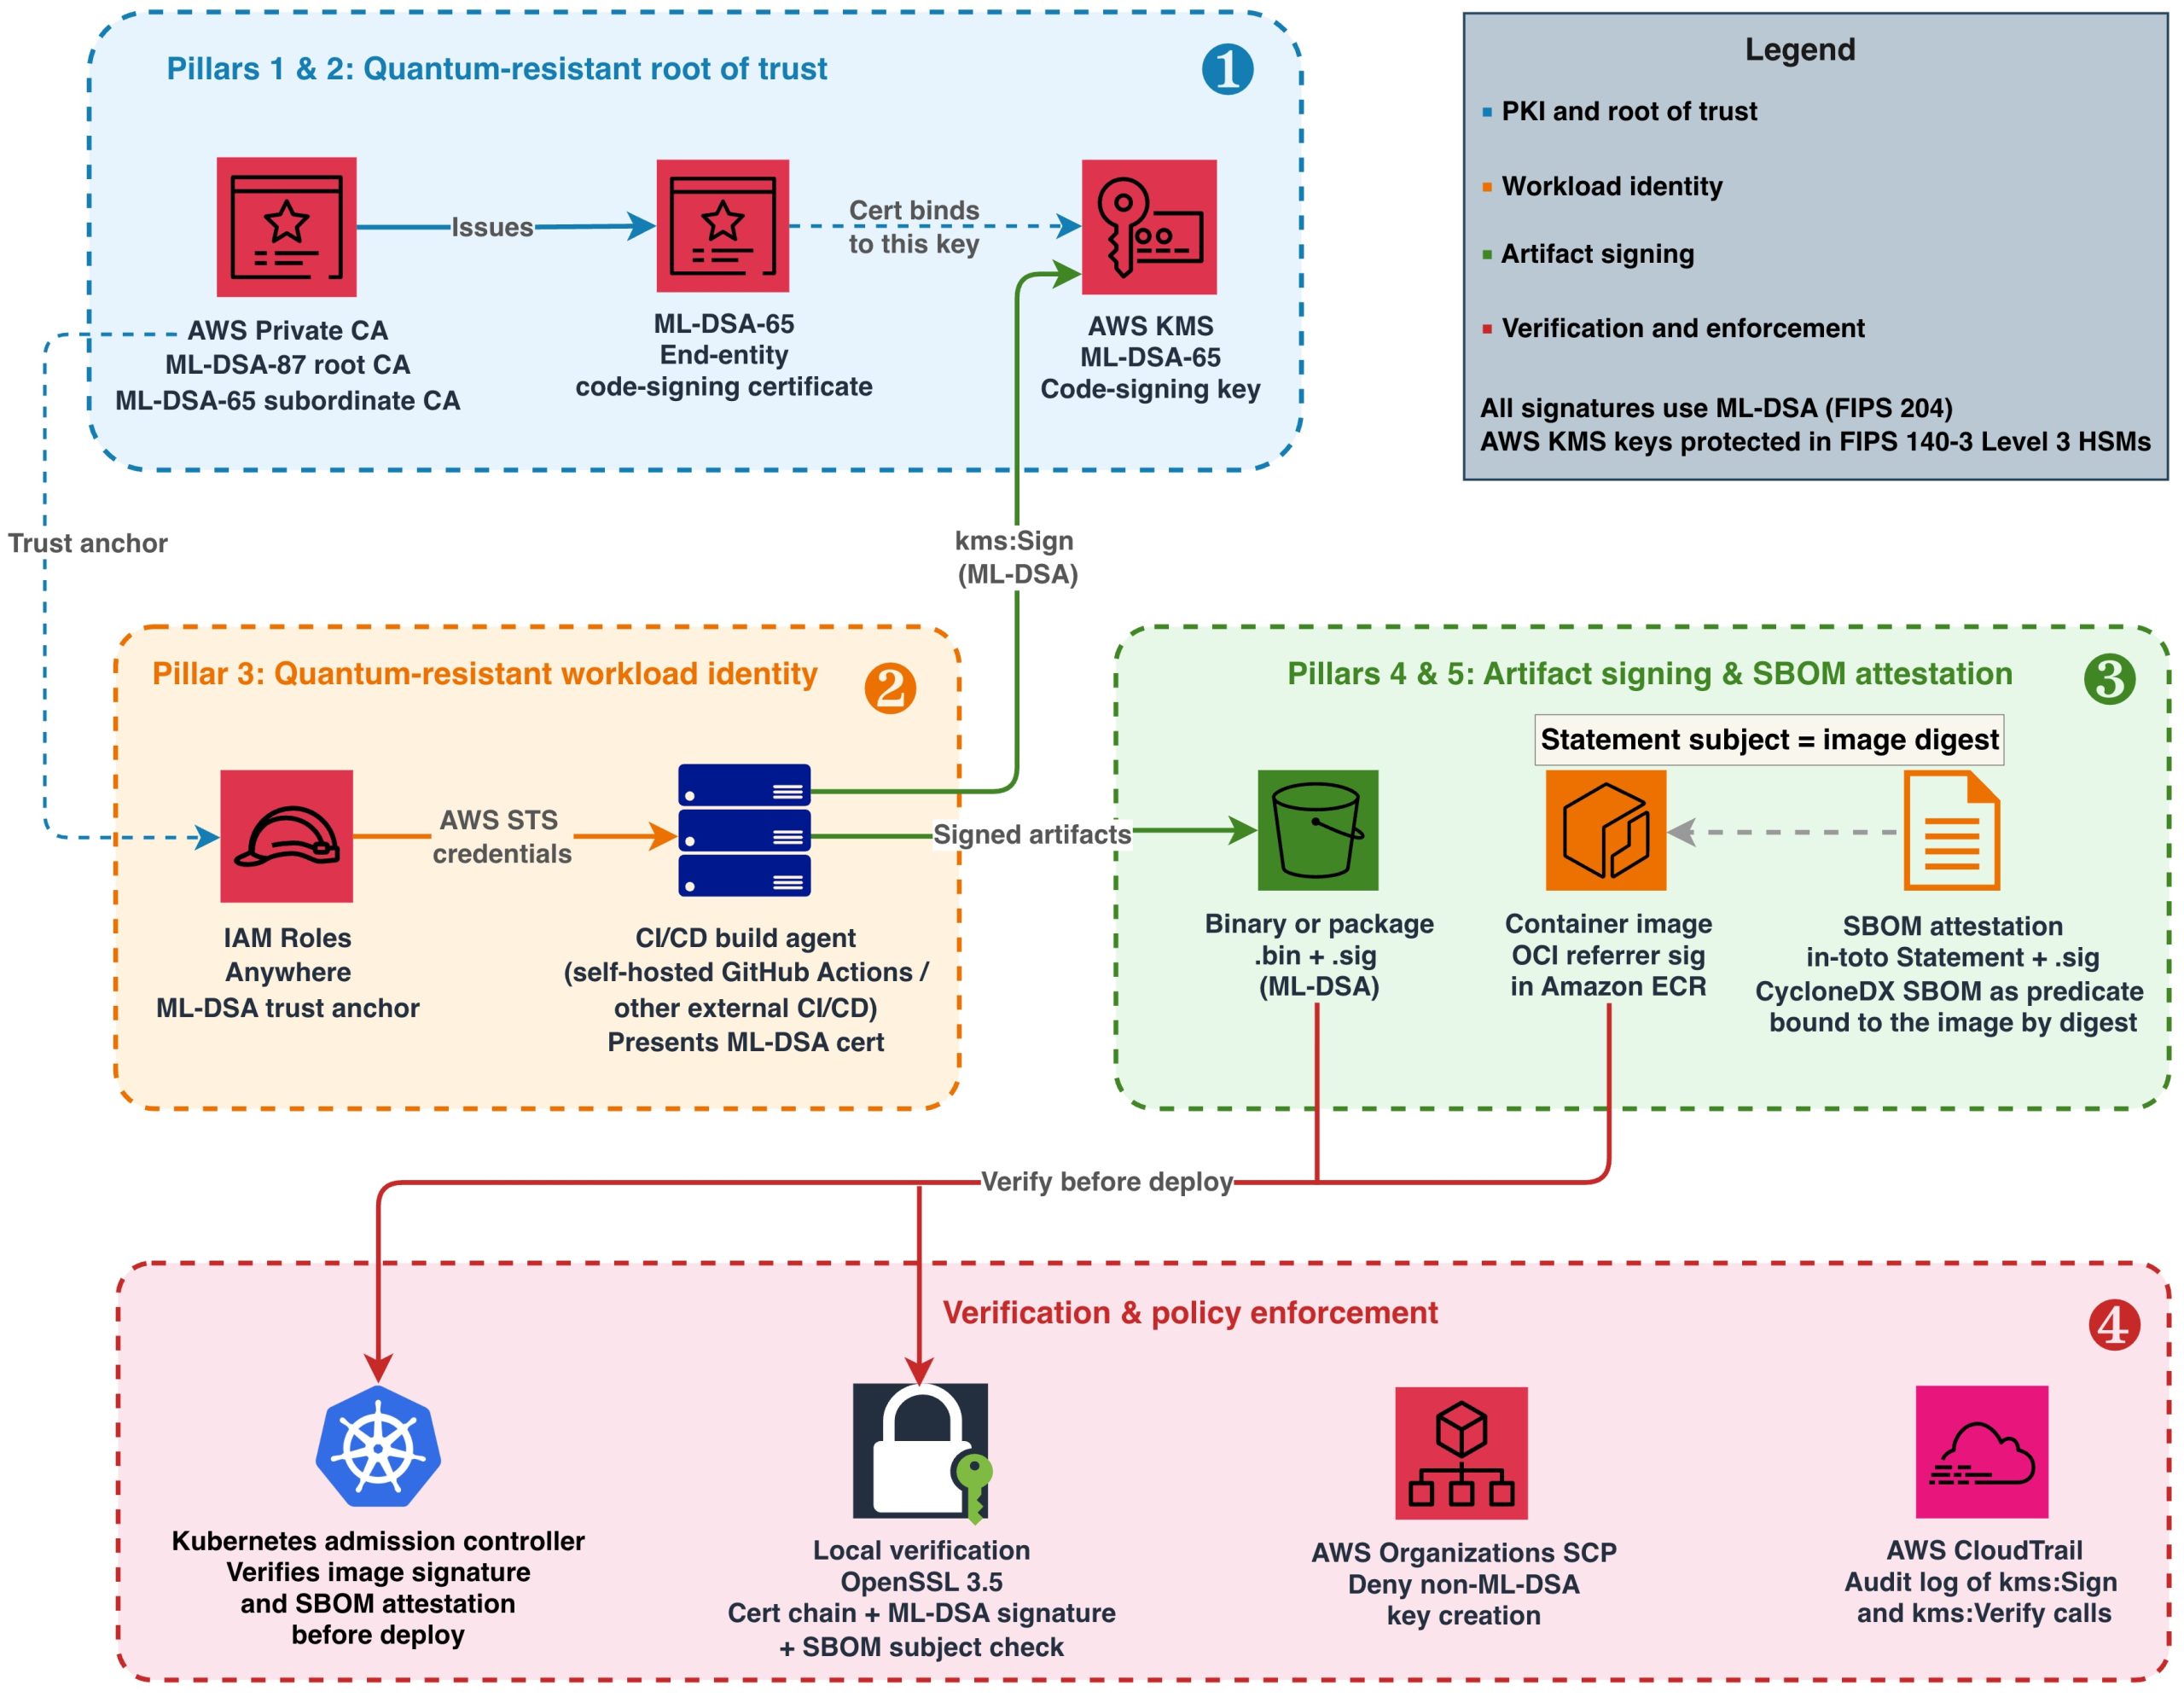
Figure 1: End-to-end quantum-resistant software supply chain on AWS

Figure 1: End-to-end quantum-resistant software supply chain on AWS

Figure 1 illustrates this architecture in four layers, numbered in the order you build them:

  1. Root of trust (Pillars 1 and 2) – Establish your AWS Private CA hierarchy and create your code-signing key in AWS KMS.
  2. Workload identity (Pillar 3) – Register the CA as an IAM Roles Anywhere trust anchor and issue ML-DSA certificates to build agents, ensuring the signer’s identity chains back to the same quantum-resistant root of trust.
  3. Artifact signing (Pillars 4 and 5) – Sign binaries, container images, and SBOMs using the authenticated build agent.
  4. Verification and enforcement – Validate signatures at deployment and enforce ML-DSA-only policies.

Prerequisites

To follow along, you need:

  • An AWS account with permissions to create resources in AWS KMS, AWS Private CA, IAM Roles Anywhere, and Amazon ECR.
  • AWS Command Line Interface (AWS CLI) v2 configured with appropriate credentials.
  • IAM Roles Anywhere credential helper (aws_signing_helper) v1.8.0 or later, the first release that supports ML-DSA keys and certificates, for workload authentication. Download from the IAM Roles Anywhere documentation.
  • OpenSSL 3.5 or later (required for ML-DSA signature verification and mu computation).
  • ORAS CLI v1.2 or later (for attaching Open Container Initiative (OCI) referrer artifacts to container images). Alternatively, you can use the Notation CLI with a custom plugin or any OCI-compliant client that supports the OCI Referrers API.
  • jq, for constructing and parsing the in-toto Statements used for SBOM attestation and for parsing ORAS output.
  • Amazon Inspector SBOM Generator (Sbomgen), or another tool that produces a CycloneDX JSON SBOM, for the SBOM example. Sbomgen runs only on Linux (x86-64 and ARM64), so run that step on a Linux build agent or container. It uses the registry credentials that oras login stores in the Docker config file, and it also accepts them through --username or the INSPECTOR_SBOMGEN_USERNAME and INSPECTOR_SBOMGEN_PASSWORD environment variables.
  • Java 11 or later and Apache Maven, to run the diy-code-signing-kms-private-ca sample that produces the code-signing CSR in Step 4 of Building the ML-DSA PKI foundation.
  • A container image pushed to Amazon ECR (for the container signing example).

Building the ML-DSA PKI foundation

Start by creating the certificate hierarchy that will anchor your supply chain trust. AWS Private CA generates and stores its own CA signing keys internally in hardware-protected HSMs when you create a certificate authority. Use ML-DSA-87 (NIST security category 5, defined as at least as hard to break as exhaustive key search on AES-256) for the root CA because it protects the longest-lived trust anchor. Use ML-DSA-65 (NIST security category 3) for the subordinate CA to balance security with smaller signature sizes for frequently issued certificates.

The parameter sets used here, ML-DSA-87 and ML-DSA-65, are also the approved set in the example algorithm policy that Part 2 of this series turns into enforceable controls. If your organization has standardized on a different set, substitute it in the commands that follow; the build steps don’t change.

Step 1: Create the root CA in AWS Private CA

When you specify KeyAlgorithm: ML_DSA_87, Private CA generates an ML-DSA-87 key pair internally. You don’t need to create a separate AWS KMS key for the CA.

aws acm-pca create-certificate-authority \
  --certificate-authority-configuration '{
    "KeyAlgorithm": "ML_DSA_87",
    "SigningAlgorithm": "ML_DSA_87",
    "Subject": {
      "CommonName": "PQC Supply Chain Root CA",
      "Organization": "Example Corp",
      "Country": "US"
    }
  }' \
  --certificate-authority-type ROOT

After creation, the root CA is in PENDING_CERTIFICATE state. Activate it by self-signing its certificate. This is where you set the root CA’s validity period (10 years is typical for a root):

# Retrieve the root CA's CSR
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <root-ca-arn> \
  --output text > root-ca.csr

# Self-sign the root CA certificate (valid for 10 years)
ROOT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://root-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=3650,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/RootCACertificate/V1 \
  --query CertificateArn --output text)

# Retrieve and install the self-signed root certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $ROOT_CERT_ARN \
  --query Certificate --output text > root-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate fileb://root-ca-cert.pem

Step 2: Create a subordinate CA for code signing

aws acm-pca create-certificate-authority \
  --certificate-authority-configuration '{
    "KeyAlgorithm": "ML_DSA_65",
    "SigningAlgorithm": "ML_DSA_65",
    "Subject": {
      "CommonName": "PQC Code Signing CA",
      "Organization": "Example Corp",
      "Country": "US"
    }
  }' \
  --certificate-authority-type SUBORDINATE

After creation, the subordinate CA enters PENDING_CERTIFICATE state with no link to the root. Activate it by signing its certificate signing request (CSR) with the root CA:

# Retrieve the subordinate CA's certificate signing request
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <sub-ca-arn> \
  --output text > sub-ca.csr

# Sign the CSR using the root CA (this establishes the trust hierarchy)
SUB_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://sub-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=1825,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/SubordinateCACertificate_PathLen0/V1 \
  --query CertificateArn --output text)

# Retrieve the signed certificate and import it to activate the subordinate CA
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $SUB_CERT_ARN \
  --query Certificate --output text > sub-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate fileb://sub-ca-cert.pem \
  --certificate-chain fileb://root-ca-cert.pem

Step 3: Create the code-signing key in AWS KMS

Your build agents use this key to sign artifacts, so their IAM roles need the kms:Sign permission on it. The end-entity certificate issued by your subordinate CA binds an identity to this key’s public key.

aws kms create-key \
  --key-spec ML_DSA_65 \
  --key-usage SIGN_VERIFY \
  --description "PQC code-signing key for supply chain" \
  --tags TagKey=Purpose,TagValue=CodeSigning

Create an alias for convenient reference in your CI/CD scripts:

aws kms create-alias \
  --alias-name alias/pqc-code-signing \
  --target-key-id <key-id-from-above>

Step 4: Issue the end-entity code signing certificate

To issue a certificate, you need a CSR. Because the ML-DSA private key never leaves the AWS KMS HSM, you can’t generate the CSR locally with OpenSSL. Instead, you construct the CSR’s TBS (to-be-signed) structure containing your subject name and public key, sign it remotely by calling aws kms sign, and assemble the final CSR from those components.

For a working implementation that assembles an ML-DSA CSR around a KMS-managed private key and signs it with AWS KMS, see Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS and its diy-code-signing-kms-private-ca sample on GitHub (Java, built with Maven). There is no AWS CLI-only path for this step: the CSR must be constructed and signed in code, and the sample is the reference implementation.

After you have the code-signing.csr file, issue the certificate from your subordinate CA:

# Issue a code-signing certificate valid for one year, signed by the subordinate CA using ML-DSA-65.
# Replace <sub-ca-arn> with the ARN that create-certificate-authority returned for the subordinate CA in Step 2.
CODE_SIGNING_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --csr fileb://code-signing.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=365,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/CodeSigningCertificate/V1 \
  --query CertificateArn --output text)

# Retrieve the issued certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-arn $CODE_SIGNING_CERT_ARN \
  --query Certificate --output text > code-signing-cert.pem

This certificate binds the signer identity to the AWS KMS code-signing key material. Note that the certificate validity period (365 days in this example) determines how long verifiers can validate signatures by checking the certificate alone. AWS Private CA lets you choose the validity period of an issued certificate, as long as it ends no later than the issuing CA’s own certificate; in this example the subordinate CA certificate from Step 2 is valid for 1,825 days, so the three-year option below fits inside it. For artifacts that must remain verifiable beyond the certificate’s expiry, consider these approaches:

  • Longer certificate validity – For private PKI, code-signing certificates are commonly issued with multi-year validity (for example, Value=1095,Type=DAYS for 3 years) because you control the issuance policy.
  • Trusted timestamping (RFC 3161) – Countersign each signature with an RFC 3161 timestamp from a Time Stamping Authority (TSA) at signing time. The timestamp proves the signature was created while the certificate was valid, allowing verification indefinitely. AWS doesn’t provide a managed TSA; use a third-party TSA or operate your own.
  • Re-signing – Before a certificate expires, re-sign active artifacts with a newly issued certificate.

Distribute the certificate chain (root CA certificate, subordinate CA certificate, and end-entity certificate) to systems that need to verify your signatures.

Signing artifacts with ML-DSA in your CI/CD pipeline

With the PKI hierarchy in place, integrate ML-DSA signing into your build process. The approach depends on artifact type. ML-DSA-65 signatures are 3,309 bytes (compared to 64 bytes for ECDSA P-256), and the latency of the AWS KMS Sign operation for ML-DSA is comparable to existing asymmetric operations. The larger signature size has negligible impact when stored alongside multi-megabyte container images or packages, but is worth accounting for in size-constrained environments like embedded device images transmitted over low-bandwidth links.

Binary and package signing

Most build outputs, including compiled binaries and packages, are far larger than the 4,096-byte limit that AWS KMS places on the message passed to aws kms sign. Make the EXTERNAL_MU method your pipeline’s default: compute the 64-byte message representative (mu) externally with OpenSSL 3.5, then pass only mu to AWS KMS. This handles an artifact of any size and never needs to change as your artifacts grow. AWS KMS also accepts content directly with --message-type RAW, up to 4,096 bytes. Use RAW only for inputs whose size is fixed by construction, such as the 71-character manifest digest in the container image example that follows. An artifact that fits today is likely to outgrow the limit later, and a pipeline that depends on RAW fails when it does. Both methods produce cryptographically identical signatures. The verifier doesn’t need to know which method was used; standard ML-DSA verification applies in either case.

# Retrieve the public key
aws kms get-public-key --key-id alias/pqc-code-signing \
  --query PublicKey --output text | base64 --decode > pk.der

# Extract raw public key bytes from the DER-encoded SubjectPublicKeyInfo.
# The BIT STRING starts at offset 17 for all ML-DSA key sizes. 
# Expected output: 1,312 bytes (ML-DSA-44), 1,952 bytes (ML-DSA-65), or 2,592 bytes (ML-DSA-87).

openssl asn1parse -inform DER -in pk.der -strparse 17 -noout -out pk_raw.bin

# Compute mu per FIPS 204 Section 6.2
printf '\x00\x00' | cat - artifact.bin > m_prime.bin
openssl dgst -shake256 -xoflen 64 -binary pk_raw.bin > pk_hash.bin
cat pk_hash.bin m_prime.bin | openssl dgst -shake256 -xoflen 64 -binary > mu.bin

# Sign the mu value
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > artifact.bin.sig

Store the .sig file alongside the artifact in Amazon S3 or your package repository. Protect the integrity of both the artifact and its signature by enabling S3 Object Lock (WORM protection) or at minimum S3 Versioning with restricted write access. If an attacker can modify or delete either file, verification can’t be trusted. For comprehensive guidance, see Security best practices for Amazon S3.

Container image signing

For container image signing, use the OCI referrer pattern, defined in the OCI Image and Distribution Specifications v1.1. A referrer is an artifact, such as a signature or an SBOM, whose manifest names another image in its subject field. Registries that support the pattern, including Amazon ECR, return these artifacts when a client asks for an image’s referrers. This approach uses AWS KMS ML-DSA keys to generate the signature and stores it as a referrer of the image:

# Repository URI used by ORAS here and in the SBOM steps; replace the account ID and Region
ECR_URI=111122223333.dkr.ecr.us-east-1.amazonaws.com/myapp

# Authenticate ORAS to Amazon ECR
aws ecr get-login-password --region us-east-1 | \
  oras login --username AWS --password-stdin 111122223333.dkr.ecr.us-east-1.amazonaws.com

# Get the image manifest digest
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)

# Sign the digest. It is a fixed 71 characters, so RAW is safe here (see Binary and package signing).
# AWS CLI v2 expects blob parameters to be base64, so write the digest to a file and pass it with fileb://
echo -n "$IMAGE_DIGEST" > digest.txt
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://digest.txt \
  --message-type RAW \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > image.mldsa.sig

# Attach signature as OCI referrer using ORAS
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" \
  image.mldsa.sig:application/octet-stream

At deployment time, your admission controller retrieves the referrer artifact and verifies the ML-DSA signature before allowing the image to run. See Verifying a container image signature before deployment later in this post for the full verification workflow and admission control implementation.

SBOM signing

A software bill of materials (SBOM) is a structured inventory of every component, library, and dependency included in a software release. It lists package names, versions, suppliers, and dependency relationships. Organizations use SBOMs to track vulnerabilities, verify license compliance, and respond quickly when a compromised component is disclosed.

Signing the SBOM file on its own proves that the inventory hasn’t been tampered with since it was signed, but not which artifact it describes. If the image signature and the SBOM signature are independent of each other, an attacker who holds a legitimately signed SBOM for a clean image can present it alongside a different signed image and claim that the two correspond. Attaching the SBOM to the image as an OCI referrer doesn’t close this gap by itself, because the subject field of a referrer manifest is set by whoever pushes the referrer; it’s a discovery mechanism, not a cryptographic binding. The binding must be inside the bytes that the signature covers.

To create that binding, wrap the SBOM in an in-toto Statement before signing it. A Statement names the artifacts it describes in its subject field, by digest, and carries the SBOM as its predicate. Because the image manifest digest is part of the signed content, a verifier can confirm that the SBOM in hand was issued for exactly the image it is about to deploy, and a swapped SBOM or a swapped digest fails verification. Embedding the SBOM in the image filesystem is another way to bind the two, because the image digest then covers the SBOM bytes. This post uses the Statement approach because it also works for SBOMs generated by scanning a finished image, for artifacts that have no filesystem such as binaries and firmware, and for images that are already in your registry, and because the SBOM stays readable from the registry without pulling the image.

Generate the SBOM with your preferred tool (such as Amazon Inspector SBOM Generator (Sbomgen) for container images), wrap it in a Statement, and sign the Statement with the same EXTERNAL_MU step you use for binaries:

# Scan the pushed image by digest so the inventory describes exactly the manifest you signed.
# Sbomgen reuses the registry login from the oras login step in the previous section.
inspector-sbomgen container --image $ECR_URI@$IMAGE_DIGEST -o sbom.json

# Wrap the SBOM in an in-toto Statement whose subject is the image manifest digest.
# This puts the digest inside the signed bytes, which binds this SBOM to this image.
jq -n \
  --arg name "$ECR_URI" \
  --arg digest "${IMAGE_DIGEST#sha256:}" \
  --slurpfile sbom sbom.json \
  '{
    "_type": "https://in-toto.io/Statement/v1",
    "subject": [{"name": $name, "digest": {"sha256": $digest}}],
    "predicateType": "https://cyclonedx.org/bom",
    "predicate": $sbom[0]
  }' > sbom.statement.json

# Sign using EXTERNAL_MU (same mu computation as binary signing above,
# with sbom.statement.json as the input)
# ... compute mu from sbom.statement.json ...
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > sbom.statement.json.sig

# Attach the Statement and its signature to the image as an OCI referrer so
# verifiers discover them alongside the image signature
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" \
  sbom.statement.json:application/vnd.in-toto+json \
  sbom.statement.json.sig:application/octet-stream

Ship the Statement and its .sig file together; the SBOM itself is the Statement’s predicate field, and verifiers extract it after verification. The same pattern binds an SBOM to a binary or package: set the subject digest to the SHA-256 of the file instead of an image manifest digest. The Verifying a binary or SBOM signature section later in this post walks through the full verification workflow, including the subject check that completes the binding.

Quantum-resistant workload identity for build agents

Signing artifacts with ML-DSA keys addresses the integrity of the artifacts themselves. Separately, build agents running outside AWS (on-premises Jenkins, self-hosted GitHub Actions runners, or third-party CI/CD systems) authenticate using X.509 certificates or OIDC tokens typically signed with RSA or ECDSA. These authentication credentials represent a classical cryptographic dependency in the pipeline. IAM Roles Anywhere with ML-DSA certificates replaces that dependency: the credential that the external build agent presents, and the CA that vouches for it, no longer rely on algorithms that are vulnerable to quantum attack. (The TLS connection that carries the request still authenticates the AWS endpoint with a traditional certificate, as public TLS does today; that is a transport concern separate from the signing identity this post is about.) Build agents running on AWS with an attached IAM role don’t have this dependency: their API requests are authenticated with AWS Signature Version 4 (SigV4), which uses a symmetric hash-based message authentication code (HMAC-SHA256). Symmetric schemes like this are already considered quantum-resistant, so no additional action is needed.

Step 1: Register a workload identity CA as a trust anchor

For this walkthrough, reuse the subordinate CA that you created earlier; that avoids the monthly charge for a second CA, and the commands that follow assume it. In production, use a dedicated subordinate CA for workload identity certificates, separate from your code-signing CA. This limits the blast radius if either CA is compromised and has to be revoked, and it lets you apply different issuance policies to the two certificate types.

# Use the ARN that create-certificate-authority returned when you created the
# subordinate CA earlier. If you no longer have it, list your CAs and copy the
# ARN of the SUBORDINATE one.
aws acm-pca list-certificate-authorities \
  --query "CertificateAuthorities[?Type=='SUBORDINATE'].[Arn,Status,CertificateAuthorityConfiguration.Subject.CommonName]" \
  --output table
SUB_CA_ARN=arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/abc-123   # replace with yours

# Register the subordinate CA as an IAM Roles Anywhere trust anchor
aws rolesanywhere create-trust-anchor \
  --name "PQC-CI-CD-Trust-Anchor" \
  --source "sourceType=AWS_ACM_PCA,sourceData={acmPcaArn=$SUB_CA_ARN}" \
  --enabled

Step 2: Create the build agent role and a profile that references it

An IAM Roles Anywhere profile specifies which IAM roles a workload can assume after it authenticates with a certificate from your trust anchor. Create the role first. Its trust policy lets IAM Roles Anywhere assume it only through your trust anchor and only for a certificate whose subject common name identifies the build agent; without those conditions, any certificate that the trust anchor CA issues could assume the role. Its permissions policy grants only what signing requires, on only the code-signing key. Save the trust policy as build-agent-trust.json, replacing the trust anchor ARN with the one that create-trust-anchor returned in Step 1:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {"Service": "rolesanywhere.amazonaws.com"},
      "Action": ["sts:AssumeRole", "sts:TagSession", "sts:SetSourceIdentity"],
      "Condition": {
        "ArnEquals": {
          "aws:SourceArn": "arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id"
        },
        "StringEquals": {
          "aws:PrincipalTag/x509Subject/CN": "pqc-build-agent-01"
        }
      }
    }
  ]
}

Save the permissions policy as build-agent-permissions.json, replacing the resource with your key’s ARN (aws kms describe-key --key-id alias/pqc-code-signing --query KeyMetadata.Arn --output text):

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["kms:Sign", "kms:GetPublicKey", "kms:DescribeKey"],
      "Resource": "<code-signing-key-arn>"
    }
  ]
}

Create the role, attach the policy, and then create a profile that references the role:

aws iam create-role \
  --role-name PQCBuildAgentRole \
  --assume-role-policy-document file://build-agent-trust.json

aws iam put-role-policy \
  --role-name PQCBuildAgentRole \
  --policy-name pqc-code-signing \
  --policy-document file://build-agent-permissions.json

aws rolesanywhere create-profile \
  --name "PQC-Build-Agent-Profile" \
  --role-arns "arn:aws:iam::111122223333:role/PQCBuildAgentRole" \
  --enabled

Step 3: Issue the build agent certificate and configure the credential helper

Generate the build agent’s ML-DSA-65 key pair and CSR locally with OpenSSL, have the subordinate CA issue a client authentication certificate for it, and then configure the IAM Roles Anywhere credential helper to present that certificate:

# Generate the build agent's key pair and CSR. The CN must match the
# aws:PrincipalTag/x509Subject/CN condition in the role's trust policy.
openssl genpkey -algorithm ML-DSA-65 -out build-agent-mldsa-key.pem
chmod 400 build-agent-mldsa-key.pem
openssl req -new -key build-agent-mldsa-key.pem \
  -subj "/C=US/O=Example Corp/CN=pqc-build-agent-01" \
  -out build-agent.csr

# Issue a 30-day client authentication certificate from the subordinate CA
# registered as the trust anchor in Step 1.
BUILD_AGENT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --csr fileb://build-agent.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=30,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/EndEntityClientAuthCertificate/V1 \
  --query CertificateArn --output text)

aws acm-pca get-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --certificate-arn $BUILD_AGENT_CERT_ARN \
  --query Certificate --output text > build-agent-mldsa.pem

# In production, store the private key in a TPM or HSM rather than as a plaintext file.
aws_signing_helper credential-process \
  --certificate build-agent-mldsa.pem \
  --private-key build-agent-mldsa-key.pem \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111122223333:profile/profile-id \
  --role-arn arn:aws:iam::111122223333:role/PQCBuildAgentRole

The helper produces short-lived AWS Security Token Service (AWS STS) credentials scoped to the build role, replacing long-lived AWS access keys. In production, protect the ML-DSA private key with hardware-backed storage such as a Trusted Platform Module (TPM), an HSM, or an encrypted credential store with restricted file permissions. The plaintext file path shown here is for demonstration purposes. The private key authorizes access to your code-signing infrastructure and should be treated with the same protection level as any signing key. On Linux build agents, at minimum restrict the file to chmod 400 owned by the service account and consider using a PKCS#11 provider to avoid storing the raw key on disk entirely.

Verification and policy enforcement

A signing architecture is only as strong as its verification. Producing signatures is half the story. The other half is giving the systems and people that deploy your artifacts, such as deployment pipelines, Kubernetes admission controllers, and engineers installing a package, a concrete way to verify those signatures and make trust decisions before an artifact is deployed or run.

Distributing your trust chain

Before any verifier can check a signature, it needs to trust the CA that issued the code-signing certificate. This trust is established through a trust store: a local collection of root CA certificates that a system treats as authoritative. Trust stores exist in operating systems (such as /etc/pki/ca-trust/ on Linux, Keychain on macOS), language run-times (Java cacerts), container base images, and custom application configurations.

For private PKI hierarchies like the one in this post, your root CA certificate isn’t in any default public trust store. You must explicitly add it to the trust stores of every system that will verify your signatures. Common approaches include:

  • Baking the root CA certificate into your container base images during the build process
  • Distributing it through configuration management (AWS Systems Manager Parameter Store, AWS Secrets Manager, or your existing configuration tooling)
  • Publishing it to an internal S3 bucket with versioning and access logging
  • Storing it as an OCI artifact in Amazon ECR alongside the images it protects

Treat trust store management with the same rigor as credential management. If an attacker can inject a rogue root certificate into your trust stores, they can make forged signatures appear valid. Restrict write access to trust stores and audit changes through AWS CloudTrail or your system-level audit logs.

Exporting your certificate chain requires exporting the root CA, and then any subordinate CAs that issue certificates that will be involved in verifying signatures:

# Export the root CA certificate
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --query Certificate --output text > root-ca.pem

# Export the subordinate CA certificate. Select only the Certificate field: for a
# subordinate CA this call also returns CertificateChain, and --output text would
# print both on one tab-separated line, producing a file that OpenSSL can't parse.
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --query Certificate --output text > sub-ca.pem
  
# Bundle the full chain for verifiers
cat root-ca.pem sub-ca.pem > trust-chain.pem

Verifiers use this chain to confirm that the code-signing public key was issued by a CA they trust.

The CAs in this post are created without a revocation configuration, and the verification commands that follow don’t check revocation status, which keeps the walkthrough short. In production, configure a certificate revocation list (CRL) or an Online Certificate Status Protocol (OCSP) responder on the subordinate CA (see Plan your AWS Private CA certificate revocation method in the AWS Private CA User Guide; both work with ML-DSA CAs). If you use a CRL, distribute it alongside the trust chain and add -crl_check -CRLfile <crl-file> to the openssl verify command below, where <crl-file> is the CRL that AWS Private CA publishes to your S3 bucket, so that a revoked code-signing certificate fails verification.

Verifying a binary or SBOM signature

Verify the code-signing certificate against the trust chain, confirm that it is a code-signing certificate issued to the signer you expect, extract its public key, and then verify the signature with OpenSSL 3.5. The second check matters: a chain check alone accepts every certificate that the CA hierarchy has issued, including the build agent client certificates from the previous section, so pin the expected subject in your verifier configuration:

# Step 1: Verify that the code-signing certificate chains to the trusted root CA and carries the
# Code Signing extended key usage. -purpose codesign (OpenSSL 3.2 and later) rejects a certificate
# that chains correctly but was issued for another purpose, such as a build agent's client
# authentication certificate from the same subordinate CA.
# trust-chain.pem contains the root CA and subordinate CA certificates distributed in the previous section.
openssl verify -CAfile trust-chain.pem -purpose codesign code-signing-cert.pem
# Confirm that the certificate was issued to the signer you expect. Replace <signer-cn> with the
# common name in your code-signing certificate's subject.
openssl x509 -in code-signing-cert.pem -noout -subject -nameopt RFC2253 | grep -q "CN=<signer-cn>" || { echo "Unexpected signer"; exit 1; }

# Step 2: Extract the public key from the verified certificate.
openssl x509 -in code-signing-cert.pem -pubkey -noout > signing-key.pem

# Step 3: Verify the artifact signature using the trusted public key.
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in artifact.bin \
  -sigfile artifact.bin.sig \
  -rawin

A successful verification prints Signature Verified Successfully and returns an exit status of 0. A failed verification prints Signature Verification Failure and returns a nonzero exit status. In shell scripts, check the exit status of each command, or run the block with set -e, so that a failed certificate chain check stops the script before signature verification and a failed signature check blocks downstream actions.

For an SBOM, run the same three steps with sbom.statement.json as the -in file and sbom.statement.json.sig as the -sigfile, then add a fourth: confirm that the subject digest inside the verified Statement is the digest of the artifact you are about to deploy. Signature verification proves the Statement is authentic; the subject check proves it describes this artifact and not another one. The digest you compare against must come from the artifact itself, resolved from the registry for an image or computed from the file for a binary, never from the Statement. For an image, this is the same digest you verify the image signature against, so the two checks together establish that this SBOM describes this signed image.

# Step 4 (SBOM only): the signed Statement must name the image being deployed.
# Resolve the digest from Amazon ECR, not from the Statement.
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)
SUBJECT_DIGEST=$(jq -r '.subject[0].digest.sha256' sbom.statement.json)
[ "sha256:$SUBJECT_DIGEST" = "$IMAGE_DIGEST" ] || { echo "SBOM does not describe this image"; exit 1; }

# Only now extract the SBOM for downstream tooling
jq '.predicate' sbom.statement.json > sbom.json

For a binary, compare the subject digest to the output of sha256sum artifact.bin instead. Reject the SBOM if either the signature or the subject check fails.

Verifying a container image signature before deployment

Pull the ML-DSA signature from the OCI referrer artifact in Amazon ECR, then verify it against the image manifest digest:

# Pull the signature referrer. ORAS 1.2 lists referrers under "manifests";
# ORAS 1.3 and later list them under "referrers". The jq filter accepts either.
oras discover $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" --format json | \
  jq -r '(.referrers // .manifests)[0].digest' | \
  xargs -I{} oras pull $ECR_URI@{} -o /tmp/sig/

# Re-derive the image digest and verify
echo -n "$IMAGE_DIGEST" > /tmp/digest.txt
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in /tmp/digest.txt \
  -sigfile /tmp/sig/image.mldsa.sig \
  -rawin

# Exit code 0 = image is authentic; non-zero = reject deployment

The same oras discover command with --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" retrieves the SBOM attestation and its signature; verify them as described in the previous section, including the subject check. The jq filter shown takes the first referrer of the requested type. Don’t rely on the order in which a registry lists referrers, and expect more than one after an image has been re-signed: a production verifier should check every referrer of that type and accept the image if at least one signature verifies against a certificate that chains to your trust store. Taking only the first can reject a correctly signed image, but it can never accept an unsigned one.

To enforce these checks at deployment time, run them in a Kubernetes admission controller, a component that the API server calls before it accepts a pod and that can reject the request. You can write one as a validating admission webhook (see Dynamic Admission Control in the Kubernetes documentation), or use Open Policy Agent (OPA) Gatekeeper, an admission webhook that enforces policies evaluated by the OPA policy engine, and package the verification steps as a Gatekeeper external data provider that a constraint calls. For a worked example of gating Amazon EKS deployments on image signatures, see Announcing Container Image Signing with AWS Signer and Amazon EKS, which verifies AWS Signer signatures at admission with Kyverno and discusses the Gatekeeper and custom webhook alternatives. The ML-DSA signature referrer in this post is a custom artifact type that those tools don’t verify out of the box, so the verification steps in this section run in code you supply. In either design, the controller runs before any pod is scheduled, rejecting images that lack a valid ML-DSA signature referrer in Amazon ECR or whose SBOM attestation doesn’t name the image being deployed.

Preventive and detective controls

Signature verification stops the use of an untrusted artifact at deployment. Organization-level controls apply earlier and more broadly: preventive controls stop teams from creating new traditional signing keys, and detective controls record every signing operation so you can audit which principal signed each artifact and when.

Preventive guardrails. Use an AWS Organizations Service control policy (SCP) to block creation of traditional signing keys in security-critical accounts, forcing all new signing workloads to use ML-DSA:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "RequirePQCSigningKeys",
      "Effect": "Deny",
      "Action": "kms:CreateKey",
      "Resource": "*",
      "Condition": {
        "StringNotLike": {
          "kms:KeySpec": "ML_DSA_*"
        },
        "StringEquals": {
          "kms:KeyUsage": "SIGN_VERIFY"
        }
      }
    }
  ]
}

This SCP prevents teams from creating new RSA or ECDSA signing keys, enforcing quantum-resistant signatures as the only option for new workloads. Note that this SCP constrains the algorithm family, not the parameter set: it would still permit an ML-DSA-44 key, which this architecture doesn’t use. Part 2 of this series picks up at exactly this point. It shows how to express a complete algorithm policy (in its example, approve ML-DSA-65 and ML-DSA-87 and exclude ML-DSA-44) as layered controls using the kms:KeySpec condition key in SCPs, IAM permission boundaries, and AWS KMS key policies; how to restrict the use of keys that already exist; and how to govern surfaces such as AWS Private CA that have no algorithm condition key. This SCP and the parameter-set SCP in Part 2 work together: attach both, and every new signing key must use an approved parameter set.

Audit trail. AWS CloudTrail logs every kms:Sign and kms:Verify API call, providing an immutable record of when each artifact was signed and by which principal. Use an organization trail and query its logs with Amazon Athena to analyze signing activity across accounts and correlate it with your deployment events.

Regulatory timeline and recommended actions

The following table maps regulatory milestones to specific actions you can take today using the architecture described in this post. This information is provided for general awareness only and does not constitute legal or compliance advice. Consult your legal and compliance teams to determine your organization’s specific obligations. For a broader overview of global PQC regulatory timelines, see Migrating to Post-Quantum Cryptography.

Regulation Deadline Regulatory language Action on AWS
CNSA 2.0: Support and prefer 2025 (in effect) CNSA 2.0 timeline (Sep 2022, FAQ v2.1 Dec 2024): Software and firmware signing must “support and prefer” CNSA 2.0 algorithms by 2025 Create ML-DSA keys in AWS KMS, begin signing artifacts with ML-DSA alongside existing traditional signatures
CNSA 2.0: New system acquisitions January 2027 CNSA 2.0 FAQ v2.1 (Dec 2024): “All new NSS acquisitions must be CNSA 2.0 compliant at deployment, effective 1 January 2027” Full ML-DSA PKI operational, IAM Roles Anywhere trust anchors using ML-DSA, all new builds carry ML-DSA signatures
EU Cyber Resilience Act 11 December 2027 Regulation (EU) 2024/2847, Annex I, Part I(2)(f): Products must “protect the integrity of stored, transmitted or otherwise processed data, personal or other, commands, programs and configuration against any manipulation or modification not authorised by the user, and report on corruptions”; Part II(7): Manufacturers must “provide for mechanisms to securely distribute updates” ML-DSA code signing for all software updates shipped to EU markets, signed SBOMs accompany every release
CNSA 2.0: Exclusive use 2030 CNSA 2.0 timeline: Software and firmware signing must “exclusively use” CNSA 2.0 algorithms by 2030 Remove traditional signing keys from supply chain, SCP enforcement of ML-DSA-only key creation
PCI DSS 4.0 Req 12.3.3 Mandatory since March 2025 PCI DSS v4.0.1, Requirement 12.3.3: “Cryptographic cipher suites and protocols in use are documented and reviewed at least once every 12 months”, including an up-to-date inventory of the cipher suites and protocols in use Document cryptographic inventory in AWS KMS, tag ML-DSA versus traditional keys, maintain migration progress tracking

Note for NSS customers and other CNSA 2.0 adopters: CNSA 2.0 is the quantum-resistant algorithm suite that the NSA requires for NSS, the federal systems that carry classified information or support intelligence, cryptologic, military command and control, and weapons functions. When ML-DSA is used for any signature purpose, including software and firmware signing, CNSA 2.0 permits only the ML-DSA-87 parameter set. (For software and firmware signing it also approves the stateful hash-based schemes LMS and XMSS, which this post doesn’t cover.) The ML-DSA-65 parameter set used in this post’s code-signing examples is appropriate for commercial workloads but isn’t permitted on NSS. CNSA 2.0 is binding only for NSS, but it’s followed voluntarily well beyond that boundary: by suppliers to the US defense and intelligence market, in the United States and allied countries, whose products must meet NSS requirements, and by commercial organizations in and outside the United States that adopt it as a conservative baseline because it specifies the highest NIST security category and removes the need to revisit parameter choices later. If your systems fall under CNSA 2.0 scope, or you’ve chosen to align with it, substitute ML-DSA-87 for all signing keys and certificates. Part 2 of this series shows how to make that substitution enforceable: the same kms:KeySpec controls that exclude ML-DSA-44 in its example can be pointed at ML_DSA_87 as the only approved key spec.

For organizations serving both US government and EU commercial markets, the January 2027 and December 2027 deadlines converge into a single migration window. Starting now provides margin for testing, key rotation planning, and certificate chain validation.

Clean up

You created a number of cryptographic resources in the prior steps and examples. AWS Private CA charges a monthly fee per CA and AWS KMS charges per key per month. To avoid ongoing charges, delete them if you aren’t actively using them. Start by listing what exists, so that you catch every resource you created, including duplicates from repeated runs. These commands list one Region; if you worked in more than one, repeat them with --region for each.

# List every private CA with its type, status, key algorithm, and subject.
# A CA you already deleted shows DELETED until its restoration window ends.
aws acm-pca list-certificate-authorities \
  --query 'CertificateAuthorities[].[Arn,Type,Status,CertificateAuthorityConfiguration.KeyAlgorithm,CertificateAuthorityConfiguration.Subject.CommonName]' \
  --output table

# List every ML-DSA key in AWS KMS with its state and creation date.
# A key already scheduled for deletion shows PendingDeletion.
for KEY_ID in $(aws kms list-keys --query 'Keys[].KeyId' --output text); do
  aws kms describe-key --key-id "$KEY_ID" \
    --query 'KeyMetadata.[KeyId,KeySpec,KeyState,CreationDate]' --output text
done | grep ML_DSA

# Show which alias points at which key. A key that no alias points at
# is usually a leftover from an earlier run.
aws kms list-aliases --query 'Aliases[].[AliasName,TargetKeyId]' --output text | grep -v '^alias/aws/'

AWS Private CA has no command that lists the certificates a CA has issued. If you need serial numbers for the revocation step that follows, generate an audit report with aws acm-pca create-certificate-authority-audit-report, which writes a list of every certificate the CA has issued or revoked to an S3 bucket that grants the service write access.

Delete each resource that you don’t need, including any extra copies that the listing revealed, then run the listing again to confirm that nothing is left:

# Revoke any issued end-entity certificates while the subordinate CA is still active
aws acm-pca revoke-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-serial <serial-number> \
  --revocation-reason CESSATION_OF_OPERATION

# Delete the IAM Roles Anywhere resources that reference the CA
aws rolesanywhere delete-profile --profile-id <profile-id>
aws rolesanywhere delete-trust-anchor --trust-anchor-id <trust-anchor-id>

# Delete the build agent role that the profile referenced, and the local copy of its private key
aws iam delete-role-policy --role-name PQCBuildAgentRole --policy-name pqc-code-signing
aws iam delete-role --role-name PQCBuildAgentRole
rm -f build-agent-mldsa-key.pem

# Delete the AWS KMS code-signing key (schedule 7-day waiting period).
# ScheduleKeyDeletion doesn't accept an alias, so resolve the key ID first.
KEY_ID=$(aws kms describe-key --key-id alias/pqc-code-signing \
  --query KeyMetadata.KeyId --output text)
aws kms schedule-key-deletion --key-id $KEY_ID --pending-window-in-days 7

# Remove the alias. It survives key deletion and would otherwise show up in the
# listing above on your next run.
aws kms delete-alias --alias-name alias/pqc-code-signing

# Disable and delete the subordinate CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --permanent-deletion-time-in-days 7

# Disable and delete the root CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --permanent-deletion-time-in-days 7

If you are adapting this for long-term use, plan for log retention. CloudTrail Event History keeps only the last 90 days of management events and is not a substitute for a trail. For the audit trail described earlier, create a trail that delivers to an S3 bucket with the lifecycle policy and access controls your retention requirements call for.

Conclusion

In this post, I showed you how to build a quantum-resistant software supply chain on AWS by combining ML-DSA signing in AWS KMS, ML-DSA certificate hierarchies in AWS Private CA, and ML-DSA workload authentication through IAM Roles Anywhere. The architecture covers the full pipeline; from authenticated build agents through signed binaries, container images, and SBOMs, to verification and policy enforcement at deployment.

Every ML-DSA capability used in this post is generally available. AWS Private CA and IAM Roles Anywhere support ML-DSA in all commercial AWS Regions, the AWS GovCloud (US) Regions, and the China Regions, and AWS KMS supports ML-DSA in commercial AWS Regions. You don’t need to wait for a standards body or third-party tool to finalize PQC support. The primitives are ready.

To get started, create your first ML-DSA key in AWS KMS and sign a test artifact. From there, extend to your PKI hierarchy, integrate IAM Roles Anywhere for your build agents, and add ML-DSA signatures to your container and SBOM workflows.

Building the pipeline is half the work. The other half is making sure the algorithm choices you made stay in force as accounts, teams, and standards change. That’s the subject of Part 2 of this series, Enforce your ML-DSA algorithm policy with SCPs and IAM, written for the security and governance teams who own that problem.

For more information, see:

If you have feedback about this post, submit comments in the Comments section below.

Harshvardhan Chunawala

Harshvardhan Chunawala

Harshvardhan is a Solutions Architect and Security SME at AWS, where he leads cross-team efforts with Amazon Leo, Amazon Security, and AWS Agentic AI. A Golden Jacket awardee with over a decade in cloud security, he’s an advisory board member, Visiting Faculty, and researcher at Carnegie Mellon University. He advises C-suite executives, enterprise leaders, and startup founders worldwide on building secure, scalable cloud platforms.

Audit trails for autonomous agents with AWS DevOps Agent

Post Syndicated from Ben Peterson original https://aws.amazon.com/blogs/devops/audit-trails-for-autonomous-agents-with-aws-devops-agent/

Autonomous agents need audit trails. AWS DevOps Agent (DevOps Agent) investigates production incidents and proposes or applies fixes on your behalf. Every operation and security review then raises the same two questions: what did the agent do, and how do you understand its impact?

AWS DevOps Agent maintains an immutable, step-by-step record of its own reasoning and actions. This post shows how to capture the agent’s full operational trail using the agent journal, recommendations, Amazon EventBridge lifecycle events, and AWS CloudTrail. We then wire them into an audit pipeline built on Amazon EventBridge, AWS Lambda, and Amazon Simple Storage Service (Amazon S3).

By the end, you will have deployable audit patterns that show, for any investigation the agent runs, what it concluded, what it recommended, when it ran, and whether the fix landed.

Why auditing an autonomous agent is different

CloudTrail records the API calls made in your account, but an autonomous agent adds reasoning that CloudTrail doesn’t capture. “The agent ran a metric query” is far less valuable than “the agent concluded the Lambda was timing out because its security group blocks egress to the database.” The latter is a decision, and that’s what an agent audit needs to capture.

The four surfaces

AWS DevOps Agent exposes four surfaces. Two capture the agent’s output, what it found and what it advises, and two capture context: when it ran, and who configured the agent and its permissions.

The agent journal

The agent journal (API) is the heart of the audit trail. For every execution, AWS DevOps Agent records an ordered, immutable log of its reasoning step, sub-agent it dispatches, observations, findings, and root-cause summary. Journal entries cannot be modified once written, making them resistant to prompt injection and trustworthy as an audit record.

aws devops-agent list-journal-records \
  --agent-space-id <id> --execution-id <execution-id>

Each record carries a recordType: symptom, observation, finding, and investigation_summary / investigation_summary_md are what matters for audit. This is the surface you archive per investigation.

Recommendations polling

Recommendations (API) are cross-incident preventative advice. The agent generates these on a schedule through a goal, and each recommendation carries a status and a version. Each evaluation run writes new records rather than updating the previous run’s, so advice that persists week over week appears as a series of records. The superseded ones remain at whatever status they last held. “The agent recommended X, the same failure recurred Y weeks later, and here is every version of that advice in between” is something you reconstruct from the archived snapshots, because the API returns current and superseded records together. Recommendations have no Amazon EventBridge event. You capture them by polling on a schedule.

aws devops-agent list-recommendations --agent-space-id <id>

Amazon EventBridge lifecycle events

Amazon EventBridge is how you capture lifecycle transitions in real time. A successful investigation produces Created, In Progress, and Completed events. Each carries the execution_id you need to fetch the journal and a summary_record_id pointing at the root-cause summary. Investigations can also end as Failed, Timed Out, or Canceled, and mitigations emit their own parallel set.

AWS CloudTrail

CloudTrail records API calls made to the AWS DevOps Agent service and stamps agent-initiated service calls: invokedBy: aidevops.amazonaws.com. It doesn’t capture the agent’s investigation reads, the metric and log queries it runs while diagnosing an incident in your account’s trail. Use CloudTrail for control-plane accountability, and the journal for behavioral audit.

IAM: Action boundary

As with anything in AWS, the agent can only do what its AWS Identity and Access Management (IAM) role permits. During an investigation, AWS DevOps Agent assumes an Agent Space role. That role’s policies are the hard ceiling on its capabilities. You can inspect it directly:

aws iam list-attached-role-policies --role-name DevOpsAgentRole-AgentSpace-<suffix>

The AWS-managed AIOpsAssistantPolicy is attached to the default role. As of policy version 15, 848 of its actions are reads except 6 read-oriented query lifecycle operations. The only actions that change anything come from a companion policy: support:CreateCase and a service-linked-role creation scoped to the Amazon Resource Name (ARN) of a single role.

Keep that role least-privilege, and your audit surface stays small by construction. If you enable agent actions, a later section covers the write path which uses a separate actions role.

The reference architecture

The agent produces output that arrives two different ways, and this shapes how you capture each:

Agent output Delivery How you capture it Latency
Investigation lifecycle Push: Amazon EventBridge events React to events (rules + targets) Seconds
Recommendations Pull: no event emitted. Generated on goal cadence Poll list-recommendations on a schedule depends on your poll frequency

The journal itself has no dedicated event, but the terminal lifecycle event carries the execution_id you need to fetch it. The journal is push-triggered, pull-retrieved: the event tells you when to look, and the API gives you what to archive.

Five capture layers inside the Agent Space Region: lifecycle events to CloudWatch Logs, terminal events to a Lambda that archives journals to Amazon S3 with a dead-letter queue, a scheduled poll for recommendations, control-plane mutations to an SNS topic through Amazon EventBridge, and a Glue/Athena query layer. Two operator CLIs read the archive: correlate.py joins findings to AWS Config and CloudTrail, and correlate_agent.py joins agent actions to their approvals.

Figure 1: Reference architecture for auditing AWS DevOps Agent across five capture layers

Layer 1: Lifecycle capture. One Amazon EventBridge rule matching {"source":["aws.aidevops"]}, targeting an Amazon CloudWatch Logs (CloudWatch Logs) group directly. This durably records every lifecycle transition. Start here for operational visibility. If your primary goal is behavioral audit rather than operational visibility, deploy layer 2 alongside it.

Layer 2: Behavior capture. A second rule matches only terminal events and invokes a Lambda function. The function reads the execution_id from the event, calls list-journal-records, and writes the journal to Amazon S3. Subscribe to each terminal investigation and mitigation type. This is the layer that captures the agent’s decisions for the long term, including agent-based mitigations.

Layer 3: Recommendations snapshot. Because recommendations are generated on a schedule and have no event, capture them with an Amazon EventBridge Scheduler rule that invokes a Lambda function on a cadence (start daily). The function calls list-recommendations and writes each to Amazon S3, keyed on recommendation ID and version. It also calls list-goals in the same invocation, because a recommendation carries no field saying whether it is still current and the owning goal is the only thing that does. The journal captures what the agent found, and this layer captures what it advised and what you did about it.

Layer 4: Control-plane alerting. On your existing organization trail, alert on mutating aidevops.amazonaws.com events including UpdateApprovalAction, which is produced on elevated actions. This is your tripwire for changes to the agent itself.

Layer 5: Query. AWS Glue Data Catalog tables and an Amazon Athena (Athena) workgroup over the archived journals, recommendations, and goals.

Querying the archive: AWS Glue and Athena

The sample implementation overlays an AWS Glue Data Catalog and an Athena workgroup on the Amazon S3 archive. Three external tables cover the full archive. The journals table uses Athena partition projection, and Hive-partitioned by agent space and date:

s3://<amzn-s3-demo-archive-bucket>/journals/space=<agent-space-id>/dt=2026-07-28/<execution-id>.json

Volume of recommendations is low (tens to hundreds of objects), so a flat external table over the recommendations/ prefix is sufficient. Athena recurses subdirectories by default, picking up every versioned snapshot.

The result bucket has Amazon S3 Object Lock but Object Lock prevents Athena from managing its own query-result objects. The query layer deploys a dedicated results bucket with a seven-day lifecycle rule for ephemeral query outputs.

Access control

Use IAM to control access. Investigation journals contain the agent’s full reasoning about your infrastructure. Scope your IAM permissions on the Athena workgroup, AWS Glue database, and on the archive bucket itself since bucket read access bypasses Athena entirely. Scope all three to your audit and operations teams.

To find all findings from the past 7 days for a specific resource:

SELECT
  execution_id,
  event_time,
  task.title,
  record.content
FROM devops_agent_audit.journals
CROSS JOIN UNNEST(journal_records) AS t(record)
WHERE dt >= date_format(current_date - interval '7' day, '%Y-%m-%d')
  AND record.recordType IN ('finding', 'investigation_result')
  AND record.content LIKE '%sg-0123456789abcdef0%'
ORDER BY event_time DESC;

The Athena workgroup integrates with Amazon Quick or any business intelligence tool that speaks JDBC/ODBC. Additional examples are available in the sample repository.

Closing the loop: Correlating findings to actual changes

The capture layers record what the agent found and what it recommended. But did the recommended fix actually land? This requires connecting the agent’s output to the real infrastructure change that followed.

The sample implementation includes correlate.py, an on-demand operator CLI that takes an archived finding or recommendation, resolves the resource it references, and reports what changed, when, and who did it. The correlation is heuristic by looking at resource identity and a tight time window in minutes to produce reliable attribution. This is why the sample implementation pairs it with a deterministic engine for agent-initiated actions.

It works by pivoting through two services:

  1. AWS Config resolves the resource identity by using select-resource-config, then pulls its configuration timeline from get-resource-config-history. This shows the before/after state of the resource around the time of the agent’s finding.
  2. CloudTrail looks up the write event that caused the change: who called what API, from where, and when. This attributes the change to a principal.

The output is a correlated record: the agent found X, the resource changed from state A to state B, and that change was made by principal Y at time T.

Because CloudTrail indexes resources by different identifiers depending on the service, you require a strategy registry. Examples are in the following table:

Resource type How CloudTrail indexes it Lookup strategy
S3 bucket Bucket name By name
Lambda function Function name By name
Amazon Relational Database Service (Amazon RDS) instance/cluster Full ARN (not the DB ID) Build ARN from template
Amazon Elastic Compute Cloud (Amazon EC2) security group Group ID as ResourceName By name, with a resource-type scan as fallback

A naive “look up by resource name” works for Amazon S3 and Lambda but returns zero results for Amazon RDS (RDS). The strategy registry encodes the right ID per resource type.

Correlating agent actions

When an operator approves an elevated action, the service stamps the approval ID into the credential it mints, so the executed call carries that ID inside its own principal ARN (op.system.apr.<approvalId>). The sample implementation includes correlate_agent.py that uses this. Because the ID is present on both sides, the correlation is a join. The engine checks the executed call against the argumentPins the operator was shown at approval time, so you can prove the agent’s behavior.

. correlate.py correlate_agent.py
Pivots on A resource the agent named Agent’s approval ID
Correlation heuristic deterministic
Answers Who changed? Who approved, and did it match?
Dependency CloudTrail and AWS Config CloudTrail

Production considerations

Understand the data volume. Journal size scales with investigation complexity. As an example:

Scenario Journal size API calls (pagination) Notes
Minimal (single-service, shallow investigation) ~65 KB 2–3 pages Quick symptom to finding arc
Typical (multi-signal, 1–2 findings) 250–340 KB 65–106 calls Typical investigations
Exhaustive (account-wide, high-priority) ~428 KB 150+ calls Full cross-service correlation

At 100 investigations/month at 300 KB average, you are storing roughly 30 MB/month of journal data.

Concurrency per agent space. By default, you can run three concurrent investigations per agent space. Additional requests queue as PENDING_START and start when a slot opens. The archival pipeline is unaffected because each terminal event triggers its own Lambda invocation. Refer to the AWS DevOps Agent Quotas page for future updates.

Paginate the journal. The journal API is server-paginated: pass limit, follow nextToken until it’s empty. A real incident’s journal can span several pages. Always loop.

Design for at-least-once delivery. Amazon EventBridge can deliver an event more than once. Key the Amazon S3 object on execution_id so a redelivery overwrites rather than duplicates, and attach an Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ) so a dropped terminal event is not lost.

Deploy per AWS Region and per account. Events land on the default bus in each Agent Space’s hosting account and Region. If you run agent spaces in multiple accounts, you must aggregate events to a central monitoring account for unified visibility. Refer to Amazon EventBridge cross-account document for further details.

Make the archive immutable. Enable Amazon S3 Object Lock and versioning. The sample implementation defaults to GOVERNANCE mode but for stronger compliance posture, use COMPLIANCE mode.

Warning: COMPLIANCE mode is irreversible. After it’s set, no principal (including the account root user) can delete or modify locked objects before their retention period expires. The only way out is closing the AWS account, and Object Lock itself can’t be disabled once enabled. Choose COMPLIANCE mode deliberately. If you use GOVERNANCE mode, enable CloudTrail data events on the bucket.

Encrypt your data. The sample implementation uses SSE-S3. If your compliance framework requires you to control and audit decryption events, use SSE-KMS with customer managed key.

The full loop

Here’s what a complete audit trail looks like for a single incident through resolution.

Step 1: Investigation. The agent investigates a failing Lambda function, concludes its security group restricts necessary egress, and writes the finding to the journal. Layer 2 archives the journal to Amazon S3.

Step 2: Recommendation. On its goal cadence, the agent generates a recommendation: “Update the security group egress rules to allow…” Layer 3 polls and captures it as recommendations/rec-a1b2c3.../v1.json with status PROPOSED. A later poll captures v2.json as the status changes.

Step 3: Engineer applies the fix. An engineer runs the suggested command. AWS Config records the new configuration item, and CloudTrail records the API call with principal, source IP, and timestamp.

Step 4: Correlation.

$ python correlate.py --archive-bucket $BUCKET \
    --recommendation rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890 \
    --window-hours 24

Recommendation: rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890
Title:          Update the Lambda security group egress rules to allow API access
Status:         PROPOSED → UPDATE_IN_PROGRESS (v2)

AWS Config change detected:

  Resource:     AWS::EC2::SecurityGroup / sg-0123456789abcdef0
  Changed:      2026-07-23 08:45:54.105000-04:00
CloudTrail attribution:
  Event:        AuthorizeSecurityGroupEgress
  Principal:    arn:aws:iam::111122223333:user/jsmith
  Source IP:    203.0.113.10
  Time:         2026-07-23 08:44:33-04:00

Correlation:    OK Recommendation → AWS Config change → CloudTrail event aligned

The agent found the problem, recommended the fix, and you can prove who applied it and when.

Step 5: A new investigation. A later investigation examines the same Lambda function, still erroring. The agent compares new advice against advice it has already given, and that comparison is semantic. But it compares against the recommendations currently attached to the goal, not against everything it has ever advised, and when the comparison is uncertain it keeps the two separate. Older advice drops out of that comparison set over time. Because you archived every recommendation and every finding with their resource identifiers, you can now compare across the full history:

$ python correlate.py --archive-bucket $BUCKET \
    --finding  exe-ops1-0f1e2d3c-4b5a-6978-8796-a5b4c3d2e1f0 \
    --check-prior-recommendations

Resource:       AWS::EC2::SecurityGroup /  sg-0123456789abcdef0

Prior recommendations referencing this resource:
   rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890 (v2, UPDATE_IN_PROGRESS):
    "Update the security group egress rules..."
   rec-b2c3d4e5-6f70-8901-bcde-f01234567890 (v1, PROPOSED):
    "Update the security group egress rules..."

! This finding may be a consequence of recommendation(s): rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890, rec-b2c3d4e5-6f70-8901-bcde-f01234567890
Last change to this resource (CloudTrail): Event: AuthorizeSecurityGroupEgress Principal: arn:aws:iam::111122223333:user/jsmith Source IP: 203.0.113.10 Time: 2026-07-23 08:44:33-04:00

The archive diagnosed the cause of the cause. Two recommendations, raised separately, on one resource, in one view. The agent’s own comparison covers the advice currently attached to the goal. The archive covers all of it. That is the feedback loop the audit trail adds.

Agent Actions changes Step 3’s actor, and the agent applies the fix directly. In the recommendation path, the human runs the command. In the elevated-action path, the human approves a specific call, and the agent executes it under a single-use session. correlate_agent.py uses a single-use session named for the approval (op.system.apr.<approvalId>), with invokedBy: aidevops.amazonaws.com rather than a time-window heuristic.

Operating the pipeline: Common failures

Always design for failure. Here are some common failures and how to detect and recover.

Failure Symptom Detection Recovery
Lambda timeout No archive in Amazon S3. Event in DLQ DLQ ApproximateNumberOfMessagesVisible alarm Increase timeout above the 2-minute default. Replay DLQ message which is idempotent on the execution_id key
Missed recommendation poll Gap in recommendations/ prefix with a version number skipped Periodic reconciliation: compare Amazon S3 keys against list-recommendations response Re-run poll Lambda manually (idempotent)
Amazon EventBridge delivery failure Missing lifecycle event in Layer 1 logs Layer 2 archive exists without matching Layer 1 log entry No data loss since journal already archived. Gap is in lifecycle visibility only
Amazon S3 write failure Lambda errors spike. DLQ grows Lambda error rate metric and DLQ alarm Fix IAM/bucket policy. Replay DLQ (all messages are idempotent)
AWS Config recorder stopped correlate.py returns no configuration history AWS Config recorder status alarm Re-enable recorder. Note: historical gap is permanent for the stopped period
Journal API throttled Partial archive. Lambda retries exhaust timeout Lambda error logs showing throttling exceptions Implement exponential backoff in the pagination loop. Increase timeout
Approval recorded but not executing Approval exists in CloudTrail with no corresponding write Join approvals to execution on the approval ID None needed

The highest value alarm is on the DLQ message count. A non-empty DLQ means a terminal event triggered, but the journal was not archived. Terminal events aren’t re-emitted, and the DLQ retains messages for 14 days. After that, the record is lost. The sample implementation ships this alarm at a threshold of 1, wired to an Amazon Simple Notification Service topic.

Run a reconciliation check weekly or monthly. Compare the execution_id values in the Layer 1 lifecycle log against the set of keys in the Amazon S3 journals/ prefix. Any ID in the logs but not in Amazon S3 represents a missed archive.

Limitations

Automated correlation – The current design requires a human to run correlate.py. Extend to a Lambda function that triggers on each new journal archive, cross-references the finding’s resource identifiers against the recommendations table, and alerts when a new finding touches a resource that was the subject of a prior recommendation.

Schema evolution – The Athena table definitions depend on the journal’s recordType values and content structure. If new record types appear, queries can return incomplete results without raising an error. Monitor for unknown recordType values. A query that returns zero findings for a week of active investigations is a signal that the schema moved.

Conclusion

Adopting an autonomous agent is a trust decision, and trust needs evidence. AWS DevOps Agent gives you the raw material: a journal of its reasoning, a real-time lifecycle event stream, a control-plane audit in CloudTrail, and an action boundary you can read straight from IAM. The pattern in this post assembles those into a durable, low-maintenance audit trail using services you already run.

The archive is more than compliance paperwork. With a persistent record of every finding and every recommendation, you can correlate across investigations and recommendations the agent no longer has in view, and against the present state of your infrastructure. That feedback loop is the difference between trusting the agent and understanding it.

Start with Layer 1. A single Amazon EventBridge rule to a log group gives you visibility into every investigation within minutes. Add the journal-archiving Lambda when you are ready to retain the agent’s decisions for the long term. Add the correlation layer when you want to prove that recommendations were acted on and catch the ones that created new problems.

Clone the sample repo to get started. It covers prerequisites, deploy steps, codebases, and teardown instruction. If you want the agent’s mitigations to become code, Automated incident remediation with AWS DevOps Agent and Kiro CLI builds a pipeline.


About the authors

Ben Peterson

Ben Peterson

Ben is a Senior Solutions Architect at AWS, focused on the developer experience and helping ISV customers modernize on AWS. He provides strategic guidance on using the AWS suite of services to modernize legacy systems, optimize performance, and unlock new capabilities. Connect with Ben on LinkedIn.

Jake Izumi

Jake Izumi

Jake is a Senior Solutions Architect supporting the NAMER ISV customers at AWS. Using his previous experience supporting corporate growth strategies, Jake works with business and technology leaders to innovate and grow on top of AWS. Connect with Jake on LinkedIn.

Sean Falconer

Sean Falconer

Sean is a Senior Solutions Architect at AWS, focused on agentic AI and event-driven architectures for ISV customers. His current work centers on the trust and governance patterns that let teams adopt autonomous agents in production. Connect with Sean on LinkedIn.

Validate Your Lambda Runtime with CloudFormation Lambda Hooks

Post Syndicated from Matteo Luigi Restelli original https://aws.amazon.com/blogs/devops/validate-your-lambda-runtime-with-cloudformation-lambda-hooks/

Introduction

This post demonstrates how to leverage AWS CloudFormation Lambda Hooks to enforce compliance rules at provisioning time, enabling you to evaluate and validate Lambda function configurations against custom policies before deployment. Often these policies impact the way a software should be built, restricting language versions and runtimes. A great example is applying those policies on AWS Lambda, a serverless compute service for running code without having to provision or manage servers. While AWS Lambda already manages the deprecation of runtimes, preventing you from deploying unsupported runtimes, organizations may need to provide and enforce their specific compliance rules not directly linked to the deprecation of a specific language version.

Introducing Lambda Hooks

AWS CloudFormation Lambda Hooks are a powerful feature that allows developers to evaluate CloudFormation and AWS Cloud Control API operations against custom code implemented as Lambda functions. This capability enables proactive inspection of resource configurations before provisioning, enhancing security, compliance, and operational efficiency.

Lambda Hooks provide a mechanism to intercept and evaluate various CloudFormation operations, including resource operations, stack operations, and change set operations (they can also be used with Cloud Control API, but in this post we’re focusing on CloudFormation). By activating a Lambda Hook, CloudFormation creates an entry in your account’s registry as a private Hook, allowing you to configure it for specific AWS accounts and regions. When configuring Lambda Hooks, you can specify one or more Lambda functions to be invoked during the evaluation process. These functions can be in the same AWS account and Region as the Hook, or in another Account you own, provided proper permissions are set up. The evaluation process occurs at specific points in the CloudFormation Stack lifecycle. For instance, during stack creation, update, or deletion, the configured Lambda functions are invoked to assess the proposed changes against your defined compliance rules. Based on the evaluation results, the hook can either block the operation or issue a warning, allowing the operation to proceed.

Lambda Hooks evaluate resources before they are provisioned through CloudFormation, providing a pre-emptive layer of governance. This means that non-compliant resources are caught and prevented from being deployed, rather than requiring retroactive fixes. By leveraging Lambda Hooks, organizations can automate and standardize their compliance checks across all AWS accounts and regions. This centralized approach to policy enforcement ensures consistency and reduces the overhead of managing compliance manually.

Solution Overview

The following sections demonstrate a practical use case for AWS CloudFormation Lambda Hooks, focusing on enforcing compliance rules on AWS Lambda runtimes.

Meet AnyCompany, a forward-thinking enterprise with a robust set of compliance rules governing their software development practices. Among these rules is a strict policy on the use of specific AWS Lambda runtimes.

As they continue to embrace serverless architecture, AnyCompany faces a challenge: how to prevent the deployment of Lambda functions that use non-compliant runtimes. Given their commitment to AWS CloudFormation for deploying Lambda functions, AnyCompany is keen to leverage the power of AWS CloudFormation Lambda Hooks.

We’ll explore the setup process, demonstrate the hook in action, and discuss the broader implications for maintaining compliance in a dynamic cloud environment.

Architecture

The following architecture highlights the implementation of the Lambda Hook. In this implementation, we are using AWS CloudFormation Lambda Hooks to intercept the deployment of Lambda Functions and perform the compliance checks on these resources. The Lambda Hook will interact with an AWS Lambda Function, which will perform the compliance checks. Finally, we’re using AWS Systems Manager Parameter Store to store the Configuration Parameter which contains the list of permitted Lambda Runtimes.

Figure 1: Architecture of the Solution

Figure 1: Architecture of the Solution

  1. A Developer (or a CI/CD pipeline) deploys a CloudFormation stack containing Lambda functions.
  2. CloudFormation invokes the respective Lambda Hook, which is configured to intercept operations on AWS Lambda Resources. We are setting this hook to “FAIL” deployment in case checks are not successful.
  3. The Lambda Hook checks if the runtime of the Lambda is admitted or violates Company’s compliance. To do this, it checks if the runtime is present on a pre-configured list of admitted runtimes saved as Parameter in AWS Systems Manager Parameter Store. Keep in mind that we’re using SSM Parameter Store to store the configuration for this specific example, but other alternatives may be viable as well (Amazon DynamoDB, AWS Secrets Manager, or AppConfig lambda-function-settings-check Preventive Rule)
  4. The Lambda Hook, after checking runtime compliance, replies:
    • With a failure, if the Lambda runtime is not compliant
    • With a success, if the Lambda runtime is compliant
  5. Depending on the response of the Lambda Hook, the deployment may or not take place.

Repository Structure

You can find all the code for this solution at this link. Here’s the repository structure:

.
├── README.md
├── deploy.sh
├── cleanup.sh
├── hook-lambda
│ ├── index.ts
│ ├── package.json
│ ├── services
│ │ └── parameter-store.ts
│ └── tsconfig.json
├── sample
│ ├── deploy_sample.sh
│ ├── cleanup_sample.sh
│ └── lambda_template.yml
└── template.yml
  • hook-lambda: directory containing all the code related to the CloudFormation Lambda Hook (Validation Lambda Function, and the CloudFormation template for the Solution)
  • sample: directory containing the code of the sample used to test the CloudFormation Lambda Hook
  • deploy.sh: utility script to deploy the Solution via AWS CLI
  • cleanup.sh: utility script to clean up the AWS CloudFormation Hook infrastructure via the AWS CLI
  • template.yml: AWS CloudFormation Template containing all the AWS Resources involved in the Solution

Prerequisites

You must have the following prerequisites for this solution:

  • An AWS account or sign up to create and activate one.
  • The following software installed on your development machine:
  • Install the AWS Command Line Interface (AWS CLI) and configure it to point to your AWS account.
  • Install Node.js and use a package manager such as npm.
  • Appropriate AWS credentials for interacting with resources in your AWS account.

Walkthrough

Creating the AWS Lambda Validation Function – Lambda Code

The CloudFormation Lambda Hook interacts with a specific Lambda (referred to as Validation Lambda throughout the rest of this post), which gets invoked during CloudFormation CREATE and UPDATE STACK operations involving Lambda Functions. The goal is to check if these Lambda functions have runtimes that comply with AnyCompany’s rules.

Below is the detailed description of the steps that the Validation Lambda function handler follows (the code is written in Typescript).

First, the Validation Lambda retrieves an environment variable containing the SSM Parameter Store parameter name which contains the compliant runtimes list. Additionally, safety checks ensure that only Lambda Resources are considered and that their Runtime property is defined.

Note that both safety checks could be skipped, since the Hook should already be configured to interact only with Lambda Resources and the Lambda’s Runtime property is always required. However, they remain in place to demonstrate how to retrieve this information from the Lambda Hook event in your handler.

const parameterName = process.env.PERMITTED_RUNTIMES_PARAM;
if (!parameterName) {
	throw new Error('Permitted Runtimes Parameter is not set');
}

const resourceProperties = event.requestData.targetModel.resourceProperties;
// Check if this is a Lambda function resource
if (event.requestData.targetType !== 'AWS::Lambda::Function') {
console.log("Resource is not a Lambda function, skipping");
	return {
		hookStatus: 'SUCCESS',
		message: 'Not a Lambda function resource, skipping validation',
		clientRequestToken: event.clientRequestToken
	}
}

// Check runtime version compliance
const runtime = resourceProperties.Runtime;
if (!runtime) {
	console.log("Runtime not defined, failing");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: 'Runtime is required for Lambda functions',
		clientRequestToken: event.clientRequestToken
	}
}

Then the Validation Lambda retrieves the value of the Configuration Parameter from SSM Parameter Store through a utility class called ParameterStoreService. For this post, consider that the value inside that Configuration Parameter is a list of strings, where each string contains one of the possible Lambda runtime values that you can find here (e.g. nodejs22.x,nodejs20.x,python3.11,python3.10,java17,java11,dotnet6). After retrieving the value, the Validation Lambda checks if the runtime of the Lambda Resource complies with the configured admitted runtimes. If the runtime is not compliant, you’ll receive a properly formatted response with FAILURE as hookStatus, otherwise the response will contain a SUCCESS hookStatus.

// Retrieve configuration from Parameter Store
const compliantRuntimes = await parameterStoreService.getParameterFromStore(parameterName);

// Check if Lambda runtime is permitted or not
if (!compliantRuntimes.includes(runtime)) {
console.log("Runtime " + runtime + " not compliant ");
	return {
		hookStatus: 'FAILURE',
		errorCode: 'NonCompliant',
		message: `Runtime ${runtime} is not compliant. Please use one of: ${compliantRuntimes.join(', ')}`,
		clientRequestToken: event.clientRequestToken
	}
}

return {
	hookStatus: 'SUCCESS',
	message: 'Runtime version compliance check passed',
	clientRequestToken: event.clientRequestToken
}

For more information about the possible response values of CloudFormation Lambda Hooks Lambda, have a look at this link.

Creating the validation Lambda – Lambda CloudFormation definition

The Validation Lambda function will be deployed via CloudFormation, in the same Stack with the CloudFormation Lambda Hook definition and the AWS Systems Manager Parameter Store Parameter. Here’s the fragment of the CloudFormation Template containing its definition:

# Lambda Function
ValidationFunction:
	Type: AWS::Lambda::Function
	Properties:
		Handler: index.handler
		Role: !GetAtt LambdaExecutionRole.Arn
		Code:
			S3Bucket: !Ref DeploymentBucket
			S3Key: hook-lambda.zip
		Runtime: nodejs22.x
		Timeout: 60
		MemorySize: 128
		Environment:
			Variables:
				PERMITTED_RUNTIMES_PARAM: !Ref ParameterStoreParamName

You’ll need to associate an IAM Role with proper permissions to access the AWS Systems Manager Parameter Store Parameter:

# Lambda Function Role
LambdaExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: lambda.amazonaws.com
            Action: sts:AssumeRole
      ManagedPolicyArns:
        - arn:aws:iam::aws:policy/service-role/AWSLambdaBasicExecutionRole
		
# IAM Policy to access Parameter Store
ParameterStoreAccessPolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref LambdaExecutionRole
      PolicyName: ParameterStoreAccess
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - ssm:GetParameter
            Resource: !Sub arn:aws:ssm:${AWS::Region}:${AWS::AccountId}:parameter${ParameterStoreParamName}

Creating the CloudFormation Lambda Hook

At this point, you only need to author a proper CloudFormation Lambda Hook. The Hook requires:

  • To be activated during the CREATE and UPDATE CloudFormation operations,
  • To consider only AWS::Lambda::Function CloudFormation resources
  • To act during Pre Provisioning of CloudFormation templates
  • To target Stack and Resource Operations
  • Target the already defined Lambda Validation function

Here’s the definition in the CloudFormation template:

# Lambda Hook
ValidationHook:
    Type: AWS::CloudFormation::LambdaHook
    Properties:
      Alias: Private::Lambda::LambdaResourcesComplianceValidationHook
      LambdaFunction: !GetAtt ValidationFunction.Arn
      ExecutionRole: !GetAtt HookExecutionRole.Arn
      FailureMode: FAIL
      HookStatus: ENABLED
      TargetFilters:
        Actions:
          - CREATE
          - UPDATE
        InvocationPoints:
          - PRE_PROVISION
        TargetNames:
          - AWS::Lambda::Function
      TargetOperations:
        - RESOURCE
        - STACK

Please note that the above template contains a reference to an IAM Role because the Hook requires proper permissions to call the target (Lambda Function). Here’s the IAM Role definition:

# Hook Execution Role
HookExecutionRole:
    Type: AWS::IAM::Role
    Properties:
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service: hooks.cloudformation.amazonaws.com
            Action: sts:AssumeRole

# IAM Policy for Lambda Invocation
LambdaInvokePolicy:
    Type: AWS::IAM::RolePolicy
    Properties:
      RoleName: !Ref HookExecutionRole
      PolicyName: LambdaInvokePolicy
      PolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Action:
              - lambda:InvokeFunction
            Resource: !GetAtt ValidationFunction.Arn

Configuring the compliant runtimes – Using Systems Manager Parameter Store

AWS Systems Manager Parameter Store is a secure, hierarchical storage service for configuration data management and secrets management, allowing users to store and retrieve data such as configurations, database strings etc. as parameter values.

In this specific example, we’ll leverage Parameter Store to store our permitted Lambda runtimes configuration. This configuration value is a StringList parameter, containing a comma-separated list of permitted runtimes. Here’s the fragment of the CloudFormation template that defines the Parameter:

# Parameter Store Parameter
ConfigParameter:
    Type: AWS::SSM::Parameter
    Properties:
      Name: !Ref ParameterStoreParamName
      Type: StringList
      Value: !Ref ParameterStoreDefaultValue
      Description: "Configuration for Lambda Hook"

Please note the usage of CloudFormation parameters for the ‘Name’ and ‘Value’ properties, allowing for dynamic input when deploying the CloudFormation template.

Deploying the Solution

To deploy the solution you can leverage the script deploy.sh in the root folder of the repository. This script will perform the following actions:

  • Compile and build the Validation Lambda Function
  • Create an Amazon S3 Bucket to store the CloudFormation Template
  • Upload the CloudFormation template and Lambda code to the S3 Bucket
  • Deploy the CloudFormation template

Testing the Lambda Hook

To test the CloudFormation Lambda Hook, deploy a simple testing CloudFormation template containing a Hello World Lambda function. First, test the Lambda configured with a permitted Lambda runtime, then modify the template to configure the Lambda with a non-compliant runtime.

Here’s the initial definition of the testing CloudFormation Template:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs22.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Please note that the Runtime value is nodejs22.x, which is currently in the list of permitted runtimes. The expectation is that the deployment of this function will succeed.

Deploy this template via the AWS CLI:

aws cloudformation deploy \
--template-file ./lambda_template.yml \
--capabilities CAPABILITY_IAM \
--stack-name lambda-sample

Check the CloudFormation Console:

CloudFormation Console showing successful Stack deployment

Figure 2: CloudFormation Console showing successful Stack deployment

As expected, the deployment was successful. You can also see that the CloudFormation Lambda Hook has been invoked by taking a look at the CloudWatch Logs:

Validation Lambda Function Logs with successful validation

Figure 3: Validation Lambda Function Logs with successful validation

Now modify the original sample Template in order to set a Lambda Runtime which is not inside the list of permitted runtimes:

# Lambda Function
HelloWorldFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: hello-world-function
      Runtime: nodejs18.x
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          exports.handler = async (event, context) => {
              console.log('Hello World!');
              const response = {
                  statusCode: 200,
                  body: JSON.stringify('Hello World!')
              };
              return response;
          };
      Timeout: 30
      MemorySize: 128

Deploy this template via AWS CLI with the same command used before and check the CloudFormation Console:

CloudFormation Console showing failed Stack deployment due to Hook intervention

Figure 4: CloudFormation Console showing failed Stack deployment due to Hook intervention

As expected, the deployment was not successful. The CloudFormation Lambda Hook has been invoked, and since the Lambda Runtime was not present in the permitted runtimes list, the deployment failed.

You can also see that the hook failed In the CloudWatch Logs:

Validation Lambda Function Logs with validation error

Figure 5: Validation Lambda Function Logs with validation error

Cleaning up

To clean up the resources related to the sample, you can run the script cleanup_sample.sh inside the sample folder. This script will delete the sample’s CloudFormation Template through the AWS CLI.

To cleanup the resources related to the solution described above and based on AWS CloudFormation Lambda Hook, you can leverage the script cleanup.sh in the root folder of the repository. This script will perform the following actions:

  • Delete the CloudFormation Stack
  • Empty the S3 Bucket used for the deployment of the Stack
  • Delete the S3 Bucket

Conclusion

In this post, you explored the implementation of CloudFormation Hooks to enforce runtime compliance in Lambda functions across your AWS infrastructure. By leveraging the Lambda hook’s capabilities, you learned how to create a preventative control that validates Lambda runtime configurations before deployment.

By activating the Lambda hook and implementing a custom Lambda function validator, you established an automated mechanism to ensure that only compliant runtimes are used within your organization’s Lambda functions during CloudFormation stack creation and updates. The solution’s integration with common development tools like AWS CLI, AWS SAM, CI/CD pipelines, and AWS CDK makes it straightforward to implement these controls within existing workflows, eliminating the need for manual runtime checks or post-deployment remediation.

The validation approach demonstrated in this post extends beyond Lambda runtimes and can be adapted to different AWS Resources supported by CloudFormation, allowing you to enforce policies on different infrastructure components offered by AWS.

About the author

Matteo Luigi Restelli

Matteo Luigi Restelli is an AWS Sr. Partner Solutions Architect. He mainly focuses on Italian Consulting AWS Partners and is also specialized in Infrastructure as Code, Cloud Native App Development and DevOps. Outside of work, he enjoys swimming, rock & roll music and learning something new everyday especially in Computer Science space.

Stella Hie

Stella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.

Generative AI adoption and compliance: Simplifying the path forward with AWS Audit Manager

Post Syndicated from Kurt Kumar original https://aws.amazon.com/blogs/security/generative-ai-adoption-and-compliance-simplifying-the-path-forward-with-aws-audit-manager/

As organizations increasingly use generative AI to streamline processes, enhance efficiency, and gain a competitive edge in today’s fast-paced business environment, they seek mechanisms for measuring and monitoring their use of AI services.

To help you navigate the process of adopting generative AI technologies and proactively measure your generative AI implementation, AWS developed the AWS Audit Manager generative AI best practices framework. This framework provides a structured approach to evaluating and adopting generative AI technologies and addresses important aspects such as strategy alignment, governance, risk assessment, and security and operational best practices. You can use the framework within AWS Audit Manager as you implement generative AI workloads, to measure and monitor existing workloads through Audit Manager capabilities such as automated evidence collection and customized assessment reports.

In this blog post, we’ll cover the AWS Audit Manager generative AI best practices framework and how it can help you during your generative AI journey. We’ll highlight key considerations to prioritize when deploying generative AI workloads, and discuss how the framework can facilitate auditing and compliance with generative AI-specific controls using Audit Manager.

Starting the generative AI Journey

An important consideration in preparing for the introduction of generative AI in your organization is the need to align your risk management strategies with robust mitigation measures. Examples of potential risks include the following:

  • Data quality, reliability, and bias: Poor source-data quality used to train models might lead to inconsistent, inaccurate, or biased outputs, which can have significant financial and regulatory impact for organizations. For example, a language model trained on biased data might generate text that reinforces harmful stereotypes or propagates misinformation. Similarly, training AI on biased product reviews or ratings might lead to product suggestions that don’t accurately reflect product quality or user preferences.
  • Model explainability and transparency: The opaque nature of many generative AI models makes it challenging to understand how they arrive at specific outputs or decisions. For example, if a model is used to generate creative content, such as stories or learning materials, it could be difficult to understand why certain outputs are generated, including potential biases or inappropriate content.
  • Data privacy and security: Generative AI models are trained on vast amounts of data, which might inadvertently include sensitive or personal information. For example, a model trained to generate text could potentially produce sentences that contain personal details from its training data.

AWS empowers organizations to use this technology responsibly while helping them to align with best practices. As part of enabling organizations to create a comprehensive risk management strategy for generative AI systems, AWS has built the AWS Audit Manager generative AI best practices framework which is mapped to Amazon Bedrock and Amazon SageMaker in AWS Audit Manager.

Amazon Bedrock is a managed service that enables you to create, manage, and scale machine learning (ML) and AI services while facilitating adherence to security and defined compliance requirements. Amazon SageMaker is a fully managed ML service that can build, train, and deploy ML models for extended use cases that require deep customization and model fine-tuning.

You can use this framework to facilitate your auditing and compliance requirements by taking advantage of controls for more responsible, ethical, and effective deployment of generative AI models.

The framework is organized into four pillars, as follows:

  • Data Governance: Data is the foundation of generative AI models, and the quality and diversity of the training data can significantly impact the model’s performance and output. The Data Governance pillar focuses on facilitating data management practices such as data sourcing, data quality, data privacy, and data bias.
  • Model Development: This pillar focuses on the responsible development and testing of generative AI models and covers aspects such as model architecture selection, model training, and model evaluation.
  • Model Deployment: This pillar addresses the challenges associated with deploying generative AI models in production environments and covers aspects such as model deployment strategies, infrastructure considerations, and access controls.
  • Monitoring & Oversight: This pillar focuses on the ongoing monitoring and governance of generative AI models in production environments and addresses aspects such as model performance monitoring and incident response planning.

You can also use Amazon Bedrock Guardrails to provide an additional level of control on top of the protections built into foundation models (FMs) to help deliver relevant and safe user experiences that align with your organization’s policies and principles.

Each organization’s generative AI journey is unique, influenced by factors such as industry-specific regulations, risk appetite, and scale of generative AI deployment. By integrating the framework with Amazon Bedrock or Amazon SageMaker, you can customize the controls to your organization’s unique needs, aligning your generative AI deployments with your specific risk management strategies. This customization is especially valuable for highly regulated sectors, such as the financial sector.

For example, you can map the risk of inaccurate outputs to controls related to data quality and model validation. Similarly, you can map data security risks to controls related to access management and encryption.

Let’s consider an example that uses a subset of these risks to understand how you could perform this mapping. A financial services firm decides to use generative AI models to develop a chatbot capable of understanding complex customer inquiries and providing accurate and tailored responses for their customer portal. Although chatbots can greatly enhance customer experiences and operational efficiency, they also introduce risks that you need to understand and measure, so that you can develop a corresponding mitigation strategy.

An auditor within the internal audit function of the financial organization would like to use the AWS Audit Manager generative AI best practices framework to assess compliance with the following sample of risks associated with the application:

  • Responsible: Validating that the chatbot adheres to ethical principles, such as fairness and transparency, and avoids perpetuating biases or discrimination against certain customer segments.
  • Accurate: Verifying the reliability and accuracy of the chatbot’s responses, particularly when handling sensitive financial information or providing advice on complex financial products.
  • Secure: Protecting the integrity and security of the data being used to train the generative AI model from unauthorized access and validating that sensitive customer data is segregated from data used for training.

Example mapping

We’ve provided an example mapping here that illustrates how you can use the framework within Audit Manager to develop a risk management strategy. Based on your individual control objectives and organizational requirements, you can further customize controls, and evidence collection can be automated or manually defined. The example mapping is as follows:

  • Responsible: Implement mechanisms for AI model monitoring and explainability to detect and mitigate potential biases or unfair outcomes.
    • RESPAI3.8: Document Risks and Tolerances: Define, document, and implement specific controls to address identified risks and organizational risk tolerances.
    • RESPAI3.9: Develop AI RACI: Define organizational roles and responsibilities, lines of communication, and ownership of controls to address identified risks. Ensure that this mapping, measuring, and managing of generative AI risks is clear to individuals and teams throughout the organization.
    • RESPAI3.13: Continuous Risk Monitoring: Periodically perform retrospectives and review policies and procedures to determine if new risks should be considered, and if current risks are addressed based on AI performance, incidents, and user feedback.
    • RESPAI3.15: Ethical Guidelines: Develop and adhere to ethical guidelines for the deployment and usage of generative AI models.
  • Accurate: Implement robust data quality checks, model validation processes, and ongoing monitoring to ensure the accuracy and reliability of the generative AI chatbot’s outputs.
    • ACCUAI3.4: Regular Audits: Conduct periodic reviews to assess the model’s accuracy over time, especially after system updates or when integrating new data sources.
    • ACCUAI3.6: Source Verification: Ensure that the data source is reputable, reliable, and the data is of high quality.
    • ACCUAI3.14: Quality Data Sourcing: The accuracy of generative AI largely depends on the quality of its training data. Ensure that the data is representative, comprehensive, and free from biases or errors.
  • Secure: Implement robust access controls, data encryption, and security monitoring measures to protect the generative AI chatbot system and training data.
    • SECAI3.2: Data Encryption In Transit: Implement end-to-end encryption for the input and output data of the AI models to minimum industry standards.
    • SECAI3.3: Data Encryption At Rest: Implement data encryption at rest for data that’s stored to train the AI models, and for the metadata that’s produced by AI models.

      Note: This is an example of a control that can be configured with automated evidence collection using AWS Config as the underlying data source, or further customized with additional data sources according to the scope of the control.

    • SECAI3.7: Least Privilege: Document, implement, and enforce least privileged principles when granting access to generative AI systems.
    • SECAI3.8: Periodic Reviews: Document, implement, and enforce periodic reviews of users’ access to generative AI systems.

      Note: This is an example of a control that can be configured with manual evidence collection based on the specific policies and procedures defined by each organization.

    • SECAI3.15: Access Logging: Require and enable mechanisms that allow users to request access to generative AI models. Ensure that access requests are properly logged, reviewed, and approved.

Conclusion

It’s important for institutions, especially those in highly regulated sectors, to proactively address new developments that relate to generative AI. Using the AWS Audit Manager generative AI best practices framework as part of a comprehensive risk management strategy can help you stay ahead of the curve and embrace an agile and responsible approach to generative AI.

The guidance provided by the framework, together with the capabilities of Audit Manager, Amazon Bedrock and SageMaker can help you establish secure and controlled environments for generative AI implementation, automate evidence collection and risk assessments, and monitor and mitigate potential risks. By embracing the potential of generative AI while adhering to best practices, you can position your organization at the forefront of innovation while maintaining the trust and confidence of stakeholders and customers.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Kurt Kumar
Kurt Kumar

Kurt is a Security Consultant at AWS Professional Services and is passionate about helping customers implement secure environments. He has over 14 years of experience in security assurance across audit, risk, and compliance functions and currently holds CISA, CISSP, Associate C|CISO, AWS Security Specialty, AWS Certified AI Practitioner and AWS SysOps Administrator – Associate certifications. Outside of work, he enjoys watching Formula 1 and travelling.

Proactively validate your AWS CloudFormation templates with AWS Lambda

Post Syndicated from Kirankumar Chandrashekar original https://aws.amazon.com/blogs/devops/proactively-validate-your-aws-cloudformation-templates-with-aws-lambda/

AWS CloudFormation is a service that allows you to define, manage, and provision your AWS cloud infrastructure using code. To enhance this process and ensure your infrastructure meets your organization’s standards, AWS offers CloudFormation Hooks. These Hooks are extension points that allow you to invoke custom logic at specific points during CloudFormation stack operations, enabling you to perform validations, make modifications, or trigger additional processes. Among these, the Lambda hook is a powerful option provided by AWS. This managed hook allows you to use Lambda functions to validate your CloudFormation templates before deployment. By using a Lambda hook, you can invoke custom logic to check infrastructure configurations on create or update or delete CloudFormation resources or stacks or change sets, as well as create or update operations for AWS Cloud Control API (CCAPI) resources. This enables you to enforce defined policies for your infrastructure-as-code (IaC), preventing the deployment of non-compliant resources or emitting warnings for potential issues. In this blog post, you will explore how to use a Lambda hook to validate your CloudFormation templates before deployment, ensuring your infrastructure is compliant and secure from the start.

Introducing Lambda Hook

The Lambda hook is an AWS-provided managed hook with the type AWS::Hooks::LambdaHook. It simplifies the integration of custom logic into CloudFormation stacks. This powerful feature allows you to focus on building and testing your custom logic as a Lambda function, without the complexity of creating a hook from scratch.

By using the Lambda hook, you can activate a pre-built hook and deploy your custom logic into a Lambda function using familiar tools like AWS CLI or AWS Serverless Application Model (SAM) or AWS Cloud Development Kit (CDK). This approach reduces the number of components you need to manage in your workflow, allowing for more streamlined operations. The Lambda hook also offers flexible evaluation capabilities, enabling you to respond to specific template properties or configurations as needed.

One of the key advantages of the Lambda hook is the enhanced control it provides. You can benefit from features such as VPC integration, local logging, and granular resource management, all while leveraging the power of AWS Lambda functions. To get started with the Lambda hook, you’ll need to activate it in your AWS account. This activation process eliminates the need for authoring, testing, packaging, and deploying a custom hook using the AWS CloudFormation Command Line Interface (CFN-CLI), significantly simplifying your workflow.

Example Use Case: S3 Bucket Versioning Validation

This blog post demonstrates using the Lambda hook to validate S3 Bucket versioning before deployment. While focused on S3 buckets, this approach can be applied to other resource types, properties, stack, and change set operations.

By leveraging the Lambda hook, you’ll streamline custom logic integration into your CloudFormation stacks. The process involves:

  1. Activating Lambda hook of type AWS::Hooks::LambdaHook in your account
  2. Writing a Lambda function for validation
  3. Providing the Lambda ARN as input to the hook

This example showcases how to enhance your infrastructure-as-code practices, ensuring compliant and secure deployments from the start.

Architecture

This section shows you how the Lambda hook and Lambda function work together to enhance your CloudFormation deployments.

Lambda hook and Lambda function

First, you need to create a Lambda function with the business logic to respond to the hook. Then, you need to create an IAM execution role with the necessary permissions to invoke the Lambda Function. Once you have the Lambda function and the IAM execution role, you can activate the AWS provided Lambda hook. Follow the steps in the documentation to activate a Lambda hook from the AWS console. Alternatively, you can activate it using the AWS Command Line Interface (AWS CLI) by using the activate-type and set-type-configuration commands. Lastly, you can also use AWS::CloudFormation::LambdaHook as a CloudFormation resource to activate and configure Lambda hook from a CloudFormation template. You can share this resource across your other accounts and regions using AWS CloudFormation StackSets by following this blog.

Lambda hook in action

The following diagram and explanation illustrate the step-by-step workflow of how Lambda hook integrates with your CloudFormation operations, providing a visual representation of the process from template creation to resource deployment or modification.

Lambda Hooks Architecture and its working in action

Diagram 1: Lambda hooks in action

The architecture diagram illustrates the step-by-step flow of how the Lambda hook is used during a CloudFormation stack operation.

  1. Author a template: Author a CloudFormation template, including the necessary resources to configure.
  2. Create the stack: The CloudFormation stack creation process has started, but the process of creating the defined resources in the template has not yet begun.
  3. Request is received by CloudFormation service: When a resource creation, update, or deletion is requested, the CloudFormation service receives the request.
  4. Invoke the Hook: The CloudFormation service then invokes the Lambda hook.
  5. The hook invokes your the Lambda Function: The Lambda hook, in turn, triggers the execution of the Lambda function that was defined in the hook activation.
  6. The Lambda function processes the request and responds back to the Hook: The Lambda function processes the request, performing validation, or additional tasks as required. The Lambda function then responds back to the Lambda hook.
  7. The stack workflow progresses further in either continuing the resource creation/update/deletion with/without a warning or fails: Based on the Lambda function’s output, the Lambda hook either allows the stack operation to proceed with the resource operation (for example, creation of the resource), or deny the resource operation causing a rollback of the stack.

This workflow demonstrates how Lambda hook seamlessly integrates into the CloudFormation stack deployment process, allowing you to implement custom validations, enforce policies, and extend the capabilities of your infrastructure-as-code deployments through the power of Lambda functions. By leveraging the Lambda hook and the custom Lambda function, customers can extend the capabilities of their CloudFormation deployments, enabling advanced use cases such as resource validation, or additional task execution.

Sample Deployment

This section shows you how to enable the Lambda hook, which is of type AWS::Hooks::LambdaHook, and add the business logic in the Lambda function to validate the versioning configuration of an S3 bucket. The sample solution shown in this blog post demonstrates the hook triggering for the resource type AWS::S3::Bucket, and if you want to trigger this for every resource type, then you can use the Resource filter within Hook filters configuration that can take wildcard "AWS::*::*" as a value or multiple targets of resource types for example "AWS::S3::Bucket", "AWS::DynamoDB::Table", and you’ll also want to make sure that the Lambda Function has the logic to handle the additional resource type. You can also add additional Hook targets , for example to validate your STACK or CHANGE_SET.

In the example used in this blog post, you will configure the hook and activate on create and update operations operations. For more information about TargetFilters, see Hook configuration schema and for more information about Lambda hook see here. With these modifications, you need to consider two important points: First, you will need to handle the business logic to deal with different resource types in your Lambda function code. Second, additional pricing may apply based on your resource usage, for more details see the Lambda pricing page.

Creating the Lambda Function

You can create a Lambda function in several ways – on the AWS Console, using CloudFormation, using AWS CLI, or by directly invoking the API via SDK. In this section, we will cover creating a Lambda function with a few clicks on the AWS console. See Using Lambda with infrastructure as code (IaC) for deploying Lambda Function using SAM CLI, CDK or CloudFormation.

Create the Lambda function on the AWS console by following create a Lambda function with the console instructions and use the following sample Python code.

"""Example Lambda function called by AWS::Hooks::LambdaHook."""


import logging


HOOK_INVOCATION_POINTS = [
    "CREATE_PRE_PROVISION",
    "UPDATE_PRE_PROVISION",
    "DELETE_PRE_PROVISION",
]

TARGET_NAMES = [
    "AWS::S3::Bucket",
]

LOGGER = logging.getLogger()

LOGGER.setLevel("INFO")


def lambda_handler(event, context):
  """Define the entry point of the function."""
  try:
    request = event
    
    LOGGER.info(f"Request: {request}")

    invocation_point = request["actionInvocationPoint"]
    LOGGER.info(f"Invocation point: {invocation_point}")

    target_name = request["requestData"]["targetName"]
    LOGGER.info(f"Target name: {target_name}")
    
    clientRequestToken = request["clientRequestToken"]

    if (
      invocation_point not in HOOK_INVOCATION_POINTS
      or target_name not in TARGET_NAMES
    ):
      message = (
        f"Skipping {target_name} evaluation for {invocation_point}."
      )
      LOGGER.info(message)
      payload = {
        "clientRequestToken": clientRequestToken,
        "hookStatus": "SUCCESS",
        "errorCode": None,
        "message": message,
        "callbackContext": None,
        "callbackDelaySeconds": 0,
      }
      LOGGER.debug(payload)
      return payload

    target_model = request["requestData"]["targetModel"]

    resource_properties = (
      target_model.get("resourceProperties")
      if target_model and target_model.get("resourceProperties")
      else None
    )
    LOGGER.debug(f"Resource properties: {resource_properties}")

    versioning_configuration = (
      resource_properties.get("VersioningConfiguration")
      if resource_properties
      and resource_properties.get("VersioningConfiguration")
      else None
    )
    versioning_configuration_status = (
      versioning_configuration.get("Status")
      if versioning_configuration
      and versioning_configuration.get("Status")
      else None
    )
    if (
      not resource_properties
      or not versioning_configuration
      or not versioning_configuration_status
      or not versioning_configuration_status == "Enabled"
    ):
      message = "Versioning not set or not enabled for the S3 bucket."
      LOGGER.error(message)
      payload = {
        "clientRequestToken": clientRequestToken,
        "hookStatus": "FAILED",
        "errorCode": "NonCompliant",
        "message": message,
      }
    else:
      message = "Versioning is enabled for the S3 bucket."
      LOGGER.info(message)
      payload = {
        "clientRequestToken": clientRequestToken,
        "hookStatus": "SUCCESS",
        "errorCode": None,
        "message": message,
      }

    LOGGER.debug(payload)
    return payload
  except Exception as exception:
    message = str(exception)
    payload = {
      "clientRequestToken":  event["clientRequestToken"],
      "hookStatus": "FAILED",
      "errorCode": "InternalFailure",
      "message": message,
      "callbackContext": None,
      "callbackDelaySeconds": 0,
    }
    LOGGER.error(message)
    return payload

Example event sent to Lambda by the hook

{
  "clientRequestToken": "XXXXXXXXXXXX-XXXX-XXXX-XXXX-XXXXXXXXXXXX",
  "awsAccountId": "111111111111",
  "stackId": "arn:aws:cloudformation:<AWS-Region>:111111111111:stack/example-stack/xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
  "changeSetId": "None",
  "hookTypeName": "AWS::Hooks::LambdaHook",
  "hookTypeVersion": "00000001",
  "hookModel":
    {
      "LambdaFunction": "example-hook-function-name",
    },
  "actionInvocationPoint": "CREATE_PRE_PROVISION",
  "requestData":
    {
      "targetName": "AWS::S3::Bucket",
      "targetType": "AWS::S3::Bucket",
      "targetLogicalId": "Bucket",
      "callerCredentials": "None",
      "providerCredentials": "None",
      "providerLogGroupName": "None",
      "hookEncryptionKeyArn": "None",
      "hookEncryptionKeyRole": "None",
      "targetModel":
        {
          "resourceProperties":
            {
              "PublicAccessBlockConfiguration":
                { "RestrictPublicBuckets": true, "IgnorePublicAcls": true },
              "BucketName": "XXXXXXXXXXXXXXXXXXXXXXXXXXX",
              "VersioningConfiguration": { "Status": "Enabled" },
            },
          "previousResourceProperties": "None",
        },
    },
  "requestContext": { "invocation": 1, "callbackContext": "None" },
}

Explanation of the Lambda Function code

The Lambda Function code is designed to process the event received from the Lambda hook and validate the versioning configuration of the target S3 bucket resource. Here’s a detailed explanation of the code:

  1. The function first extracts the relevant information from the event, including the invocation point and the target resource type.
  2. It then checks if the current invocation point is in the configured HOOK_INVOCATION_POINTS list and if the target resource type is AWS::S3::Bucket. If not, the function returns a success response, skipping the validation for this particular invocation.

Note: this code that skips the validation is put here as a fallback logic in the event the user has not chosen to use TargetFilters. As this is a wildcard hook, without TargetFilters the hook will always be invoked for any AWS resource type described in the template, and since the hook targets preCreate, preUpdate, and preDelete by default, the hook will be invoked for these invocation points by default. To narrow the scope and reduce costs by avoiding to invoke the hook for all AWS resource type targets and invocation points, use TargetFilters.

  1. Next, the function retrieves the resource properties from the event, specifically looking for the VersioningConfiguration property and its Status.
  2. If the VersioningConfiguration property is not present or its Status is not set to Enabled, the function returns a failure response, indicating that the versioning is not enabled for the S3 bucket.
  3. If the versioning is enabled, the function returns a success response.
  4. The function also includes a fallback mechanism to return a failure response in case of any other exceptions. By evaluating this sample code, you can validate the versioning configuration of the S3 bucket during the CloudFormation stack creation and update processes, with your infrastructure-as-code policies.

Enabling Lambda Hook in your AWS Account/Region

  1. Navigate to the AWS CloudFormation service on the AWS Console, then choose “Create Hook” → “with Lambda” from the main Hooks page:

Lambda Hooks Creation

Diagram 2: Create a Hook with Lambda console page

You will see the page explaining how the Lambda function work as a hook.

Lambda hooks provide lambda

Diagram 3: Provide a Lambda function to Hook Console page

  1. Provide the Hooks details: the name, the Lambda function it should take, the type, and the mode. You can also create your execution role directly from the console by choosing “New execution role”.
Lambdas Hooks Details Config

Diagram 3: Provide a Lambda function to Hook Console page

You can review the Lambda hook and activate it from the next page.

Lambda Hooks details and configuration

Diagram 4: Review Lambda hook Console page

Test a sample

In this section, you will test the hook and the Lambda Function that you activated for a S3 bucket resource.

Create an S3 Bucket without versioning

AWSTemplateFormatVersion: "2010-09-09"

Description: This CloudFormation template provisions an S3 Bucket without versioning enabled

Resources:
  S3Bucket:
    DeletionPolicy: Delete
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Sub test-bucket-versioning-1-${AWS::Region}-${AWS::AccountId}

You will see the hook invoking Lambda function and the Lambda Function responding back with a failure message since the Versioning is not enabled.

When you create or update a stack with the template above, the Lambda hook will be invoked, and the Lambda Function will respond with a failure message since bucket versioning is not enabled. The Lambda Function code will extract the resourceProperties from the event, check the VersioningConfiguration property, and find that the Status is not set to Enabled. As a result, if you use the example template above where you describe the S3 bucket without versioning enabled, the Lambda Function will send a failure response back to the hook, causing the CloudFormation stack operation to fail as shown in the following screenshot.

Lambda Hooks Failure stack

Diagram 5: Lambda Hook failure Stack

Create an S3 Bucket with versioning enabled You can try creating an S3 Bucket with versioning enabled to see how Hooks assessment succeeded.

AWSTemplateFormatVersion: "2010-09-09"

Description: This CloudFormation template provisions an S3 Bucket with Versioning enabled

Resources:
  S3Bucket:
    DeletionPolicy: Delete
    Type: AWS::S3::Bucket
    Properties:
      BucketName: !Sub test-bucket-versioning-2-${AWS::Region}-${AWS::AccountId}
      VersioningConfiguration:
        Status: Enabled

In this case, you will see the hook invoking the Lambda function and getting a success message since the Versioning is enabled

When you create a stack with this CloudFormation template, the Lambda hook will be invoked, and the Lambda Function will respond with a success message since the versioning is enabled. The Lambda Function code will extract the resourceProperties from the event, check the VersioningConfiguration property, and find that the Status is set to Enabled. As a result, the Lambda Function will send a success response back to the hook, allowing the CloudFormation stack operation to proceed as shown in the following screenshot.

Lambda Hooks Success stack

Diagram 6: Lambda Hook success Stack

By testing these two scenarios, you can verify that the Lambda hook and the associated Lambda Function are working as expected, enforcing the S3 bucket versioning policy during CloudFormation stack operations.

Clean up

To clean up, refer to the following documentation to delete CloudFormation Stacks: Deleting a stack on the AWS CloudFormation console or Deleting a stack using AWS CLI. Refer to documentation to deactivate the hook.

Conclusion

In this blog post, you explored the capabilities of CloudFormation Hooks and how they can be leveraged to extend the functionality of your infrastructure-as-code deployments. Specifically, you learned about the Lambda hook, a pre-built hook that simplifies the process of integrating custom logic into your CloudFormation stacks.

By activating the Lambda hook, and deploying a custom Lambda Function, you were able to validate the versioning configuration of an S3 bucket during the CloudFormation stack creation and update processes. This approach allows you to enforce infrastructure-as-code policies and ensure compliance at the point of deployment, rather than relying on post-deployment checks or indirect governance mechanisms. The ability to leverage familiar tools and workflows, such as the AWS CLI, AWS SAM, CI/CD pipelines, or the AWS CDK, makes it easier to incorporate custom logic into your CloudFormation deployments. This reduces the overhead and complexity associated with traditional hook orchestration and packaging, empowering you to streamline your infrastructure-as-code practices.

As you continue to build and deploy your cloud infrastructure, consider exploring the various CloudFormation Hooks available, for example, see aws-cloudformation/aws-cloudformation-samples and aws-cloudformation/community-registry-extensions GitHub repositories. The approach demonstrated in this blog post can be applied to other resource types supported by CloudFormation, allowing you to validate and enforce policies for a wide range of infrastructure components, from EC2 instances and VPCs to databases and application services.

About the Author

kirankumar.jpeg

Kirankumar Chandrashekar is a Sr. Solutions Architect for Strategic Accounts at AWS. He focuses on leading customers in architecting DevOps, modernization using serverless, containers and container orchestration technologies like Docker, ECS, EKS to name a few. Kirankumar is passionate about DevOps, Infrastructure as Code, modernization and solving complex customer issues. He enjoys music, as well as cooking and traveling.

stella.jpegStella Hie is a Sr. Product Manager Technical for AWS Infrastructure as Code. She focuses on proactive control and governance space, working on delivering the best experience for customers to use AWS solutions safely. Outside of work, she enjoys hiking, playing piano, and watching live shows.

Simplify risk and compliance assessments with the new common control library in AWS Audit Manager

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/simplify-risk-and-compliance-assessments-with-the-new-common-control-library-in-aws-audit-manager/

With AWS Audit Manager, you can map your compliance requirements to AWS usage data and continually audit your AWS usage as part of your risk and compliance assessment. Today, Audit Manager introduces a common control library that provides common controls with predefined and pre-mapped AWS data sources.

The common control library is based on extensive mapping and reviews conducted by AWS certified auditors, verifying that the appropriate data sources are identified for evidence collection. Governance, Risk and Compliance (GRC) teams can use the common control library to save time time when mapping enterprise controls into Audit Manager for evidence collection, reducing their dependence on information technology (IT) teams.

Using the common control library, you can view the compliance requirements for multiple frameworks (such as PCI or HIPAA) associated with the same common control in one place, making it easier to understand your audit readiness across multiple frameworks simultaneously. In this way, you don’t need to implement different compliance standard requirements individually and then review the resulting data multiple times for different compliance regimes.

Additionally, by using controls from this library, you automatically inherit improvements as Audit Manager updates or adds new data sources, such as additional AWS CloudTrail events, AWS API calls, AWS Config rules, or maps additional compliance frameworks to common controls. This eliminates the efforts required by GRC and IT teams to constantly update and manage evidence sources and makes it easier to benefit from additional compliance frameworks that Audit Manager adds to its library.

Let’s see how this works in practice with an example.

Using AWS Audit Manager common control library
A common scenario for an airline is to implement a policy so that their customer payments, including in-flight meals and internet access, can only be taken via credit card. To implement this policy, the airline develops an enterprise control for IT operations that says that “customer transactions data is always available.” How can they monitor whether their applications on AWS meet this new control?

Acting as their compliance officer, I open the Audit Manager console and choose Control library from the navigation bar. The control library now includes the new Common category. Each common control maps to a group of core controls that collect evidence from AWS managed data sources and makes it easier to demonstrate compliance with a range of overlapping regulations and standards. I look through the common control library and search for “availability.” Here, I realize the airline’s expected requirements map to common control High availability architecture in the library.

Console screenshot.

I expand the High availability architecture common control to see the underlying core controls. There, I notice this control doesn’t adequately meet all the company’s needs because Amazon DynamoDB is not in this list. DynamoDB is a fully managed database, but given extensive usage of DynamoDB in their application architecture, they definitely want their DynamoDB tables to be available when their workload grows or shrinks. This might not be the case if they configured a fixed throughput for a DynamoDB table.

I look again through the common control library and search for “redundancy.” I expand the Fault tolerance and redundancy common control to see how it maps to core controls. There, I see the Enable Auto Scaling for Amazon DynamoDB tables core control. This core control is relevant for the architecture that the airline has implemented but the whole common control is not needed.

Console screenshot.

Additionally, common control High availability architecture already includes a couple of core controls that check that Multi-AZ replication on Amazon Relational Database Service (RDS) is enabled, but these core controls rely on an AWS Config rule. This rule doesn’t work for this use case because the airline does not use AWS Config. One of these two core controls also uses a CloudTrail event, but that event does not cover all scenarios.

Console screenshot.

As the compliance officer, I would like to collect the actual resource configuration. To collect this evidence, I briefly consult with an IT partner and create a custom control using a Customer managed source. I select the api-rds_describedbinstances API call and set a weekly collection frequency to optimize costs.

Console screenshot.

Implementing the custom control can be handled by the compliance team with minimal interaction needed from the IT team. If the compliance team has to reduce their reliance on IT, they can implement the entire second common control (Fault tolerance and redundancy) instead of only selecting the core control related to DynamoDB. It might be more than what they need based on their architecture, but the acceleration of velocity and reduction of time and effort for both the compliance and IT teams is often a bigger benefit than optimizing the controls in place.

I now choose Framework library in the navigation pane and create a custom framework that includes these controls. Then, I choose Assessments in the navigation pane and create an assessment that includes the custom framework. After I create the assessment, Audit Manager starts collecting evidence about the selected AWS accounts and their AWS usage.

By following these steps, a compliance team can precisely report on the enterprise control “customer transactions data is always available” using an implementation in line with their system design and their existing AWS services.

Things to know
The common control library is available today in all AWS Regions where AWS Audit Manager is offered. There is no additional cost for using the common control library. For more information, see AWS Audit Manager pricing.

This new capability streamlines the compliance and risk assessment process, reducing the workload for GRC teams and simplifying the way they can map enterprise controls into Audit Manager for evidence collection. To learn more, see the AWS Audit Manager User Guide.

— Danilo

Deploy CloudFormation Hooks to an Organization with service-managed StackSets

Post Syndicated from Kirankumar Chandrashekar original https://aws.amazon.com/blogs/devops/deploy-cloudformation-hooks-to-an-organization-with-service-managed-stacksets/

This post demonstrates using AWS CloudFormation StackSets to deploy CloudFormation Hooks from a centralized delegated administrator account to all accounts within an Organization Unit(OU). It provides step-by-step guidance to deploy controls at scale to your AWS Organization as Hooks using StackSets. By following this post, you will learn how to deploy a hook to hundreds of AWS accounts in minutes.

AWS CloudFormation StackSets help deploy CloudFormation stacks to multiple accounts and regions with a single operation. Using service-managed permissions, StackSets automatically generate the IAM roles required to deploy stack instances, eliminating the need for manual creation in each target account prior to deployment. StackSets provide auto-deploy capabilities to deploy stacks to new accounts as they’re added to an Organizational Unit (OU) in AWS Organization. With StackSets, you can deploy AWS well-architected multi-account solutions organization-wide in a single click and target stacks to selected accounts in OUs. You can also leverage StackSets to auto deploy foundational stacks like networking, policies, security, monitoring, disaster recovery, billing, and analytics to new accounts. This ensures consistent security and governance reflecting AWS best practices.

AWS CloudFormation Hooks allow customers to invoke custom logic to validate resource configurations before a CloudFormation stack create/update/delete operation. This helps enforce infrastructure-as-code policies by preventing non-compliant resources. Hooks enable policy-as-code to support consistency and compliance at scale. Without hooks, controlling CloudFormation stack operations centrally across accounts is more challenging because governance checks and enforcement have to be implemented through disjointed workarounds across disparate services after the resources are deployed. Other options like Config rules evaluate resource configurations on a timed basis rather than on stack operations. And SCPs manage account permissions but don’t include custom logic tailored to granular resource configurations. In contrast, CloudFormation hooks allows customer-defined automation to validate each resource as new stacks are deployed or existing ones updated. This enables stronger compliance guarantees and rapid feedback compared to asynchronous or indirect policy enforcement via other mechanisms.

Follow the later sections of this post that provide a step-by-step implementation for deploying hooks across accounts in an organization unit (OU) with a StackSet including:

  1. Configure service-managed permissions to automatically create IAM roles
  2. Create the StackSet in the delegated administrator account
  3. Target the OU to distribute hook stacks to member accounts

This shows how to easily enable a policy-as-code framework organization-wide.

I will show you how to register a custom CloudFormation hook as a private extension, restricting permissions and usage to internal administrators and automation. Registering the hook as a private extension limits discoverability and access. Only approved accounts and roles within the organization can invoke the hook, following security best practices of least privilege.

StackSets Architecture

As depicted in the following AWS StackSets architecture diagram, a dedicated Delegated Administrator Account handles creation, configuration, and management of the StackSet that defines the template for standardized provisioning. In addition, these centrally managed StackSets are deploying a private CloudFormation hook into all member accounts that belong to the given Organization Unit. Registering this as a private CloudFormation hook enables administrative control over the deployment lifecycle events it can respond to. Private hooks prevent public usage, ensuring the hook can only be invoked by approved accounts, roles, or resources inside your organization.

Architecture for deploying CloudFormation Hooks to accounts in an Organization

Diagram 1: StackSets Delegated Administration and Member Account Diagram

In the above architecture, Member accounts join the StackSet through their inclusion in a central Organization Unit. By joining, these accounts receive deployed instances of the StackSet template which provisions resources consistently across accounts, including the controlled private hook for administrative visibility and control.

The delegation of StackSet administration responsibilities to the Delegated Admin Account follows security best practices. Rather than having the sensitive central Management Account handle deployment logistics, delegation isolates these controls to an admin account with purpose-built permissions. The Management Account representing the overall AWS Organization focuses more on high-level compliance governance and organizational oversight. The Delegated Admin Account translates broader guardrails and policies into specific infrastructure automation leveraging StackSets capabilities. This separation of duties ensures administrative privileges are restricted through delegation while also enabling an organization-wide StackSet solution deployment at scale.

Centralized StackSets facilitate account governance through code-based infrastructure management rather than manual account-by-account changes. In summary, the combination of account delegation roles, StackSet administration, and joining through Organization Units creates an architecture to allow governed, infrastructure-as-code deployments across any number of accounts in an AWS Organization.

Sample Hook Development and Deployment

In the section, we will develop a hook on a workstation using the AWS CloudFormation CLI, package it, and upload it to the Hook Package S3 Bucket. Then we will deploy a CloudFormation stack that in turn deploys a hook across member accounts within an Organization Unit (OU) using StackSets.

The sample hook used in this blog post enforces that server-side encryption must be enabled for any S3 buckets and SQS queues created or updated on a CloudFormation stack. This policy requires that all S3 buckets and SQS queues be configured with server-side encryption when provisioned, ensuring security is built into our infrastructure by default. By enforcing encryption at the CloudFormation level, we prevent data from being stored unencrypted and minimize risk of exposure. Rather than manually enabling encryption post-resource creation, our developers simply enable it as a basic CloudFormation parameter. Adding this check directly into provisioning stacks leads to a stronger security posture across environments and applications. This example hook demonstrates functionality for mandating security best practices on infrastructure-as-code deployments.

Prerequisites

On the AWS Organization:

On the workstation where the hooks will be developed:

In the Delegated Administrator account:

Create a hooks package S3 bucket within the delegated administrator account. Upload the hooks package and CloudFormation templates that StackSets will deploy. Ensure the S3 bucket policy allows access from the AWS accounts within the OU. This access lets AWS CloudFormation access the hooks package objects and CloudFormation template objects in the S3 bucket from the member accounts during stack deployment.

Follow these steps to deploy a CloudFormation template that sets up the S3 bucket and permissions:

  1. Click here to download the admin-cfn-hook-deployment-s3-bucket.yaml template file in to your local workstation.
    Note: Make sure you model the S3 bucket and IAM policies as least privilege as possible. For the above S3 Bucket policy, you can add a list of IAM Role ARNs created by the StackSets service managed permissions instead of AWS: “*”, which allows S3 bucket access to all the IAM entities from the accounts in the OU. The ARN of this role will be “arn:aws:iam:::role/stacksets-exec-” in every member account within the OU. For more information about equipping least privilege access to IAM policies and S3 Bucket Policies, refer IAM Policies and Bucket Policies and ACLs! Oh, My! (Controlling Access to S3 Resources) blog post.
  2. Execute the following command to deploy the template admin-cfn-hook-deployment-s3-bucket.yaml using AWS CLI. For more information see Creating a stack using the AWS Command Line Interface. If using AWS CloudFormation console, see Creating a stack on the AWS CloudFormation console.
    To get the OU Id, see Viewing the details of an OU. OU Id starts with “ou-“. To get the Organization Id, see Viewing details about your organization. Organization Id starts with “o-”

    aws cloudformation create-stack \
    --stack-name hooks-asset-stack \
    --template-body file://admin-cfn-deployment-s3-bucket.yaml \
    --parameters ParameterKey=OrgId,ParameterValue="&lt;Org_id&gt;" \
    ParameterKey=OUId,ParameterValue="&lt;OU_id&gt;"
  3. After deploying the stack, note down the AWS S3 bucket name from the CloudFormation Outputs.

Hook Development

In this section, you will develop a sample CloudFormation hook package that will enforce encryption for S3 Buckets and SQS queues within the preCreate and preDelete hook. Follow the steps in the walkthrough to develop a sample hook and generate a zip package for deploying and enabling them in all the accounts within an OU. While following the walkthrough, within the Registering hooks section, make sure that you stop right after executing the cfn submit --dry-run command. The --dry-run option will make sure that your hook is built and packaged your without registering it with CloudFormation on your account. While initiating a Hook project if you created a new directory with the name mycompany-testing-mytesthook, the hook package will be generated as a zip file with the name mycompany-testing-mytesthook.zip at the root your hooks project.

Upload mycompany-testing-mytesthook.zip file to the hooks package S3 bucket within the Delegated Administrator account. The packaged zip file can then be distributed to enable the encryption hooks across all accounts in the target OU.

Note: If you are using your own hooks project and not doing the tutorial, irrespective of it, you should make sure that you are executing the cfn submit command with the --dry-run option. This ensures you have a hooks package that can be distributed and reused across multiple accounts.

Hook Deployment using CloudFormation Stack Sets

In this section, deploy the sample hook developed previously across all accounts within an OU. Use a centralized CloudFormation stack deployed from the delegated administrator account via StackSets.

Deploying hooks via CloudFormation requires these key resources:

  1. AWS::CloudFormation::HookVersion: Publishes a new hook version to the CloudFormation registry
  2. AWS::CloudFormation::HookDefaultVersion: Specifies the default hook version for the AWS account and region
  3. AWS::CloudFormation::HookTypeConfig: Defines the hook configuration
  4. AWS::IAM::Role #1: Task execution role that grants the hook permissions
  5. AWS::IAM::Role #2: (Optional) role for CloudWatch logging that CloudFormation will assume to send log entries during hook execution
  6. AWS::Logs::LogGroup: (Optional) Enables CloudWatch error logging for hook executions

Follow these steps to deploy CloudFormation Hooks to accounts within the OU using StackSets:

  1. Click here to download the hooks-template.yaml template file into your local workstation and upload it into the Hooks package S3 bucket in the Delegated Administrator account.
  2. Deploy the hooks CloudFormation template hooks-template.yaml to all accounts within an OU using StackSets. Leverage service-managed permissions for automatic IAM role creation across the OU.
    To deploy the hooks template hooks-template.yaml across OU using StackSets, click here to download the CloudFormation StackSets template hooks-stack-sets-template.yaml locally, and upload it to the hooks package S3 bucket in the delegated administrator account. This StackSets template contains an AWS::CloudFormation::StackSet resource that will deploy the necessary hooks resources from hooks-template.yaml to all accounts in the target OU. Using SERVICE_MANAGED permissions model automatically handle provisioning the required IAM execution roles per account within the OU.
  3. Execute the following command to deploy the template hooks-stack-sets-template.yaml using AWS CLI. For more information see Creating a stack using the AWS Command Line Interface. If using AWS CloudFormation console, see Creating a stack on the AWS CloudFormation console.To get the S3 Https URL for the hooks template, hooks package and StackSets template, login to the AWS S3 service on the AWS console, select the respective object and click on Copy URL button as shown in the following screenshot:s3 download https url
    Diagram 2: S3 Https URL

    To get the OU Id, see Viewing the details of an OU. OU Id starts with “ou-“.
    Make sure to replace the <S3BucketName> and then <OU_Id> accordingly in the following command:

    aws cloudformation create-stack --stack-name hooks-stack-set-stack \
    --template-url https://<S3BucketName>.s3.us-west-2.amazonaws.com/hooks-stack-sets-template.yaml \
    --parameters ParameterKey=OuId,ParameterValue="<OU_Id>" \
    ParameterKey=HookTypeName,ParameterValue="MyCompany::Testing::MyTestHook" \
    ParameterKey=s3TemplateURL,ParameterValue="https://<S3BucketName>.s3.us-west-2.amazonaws.com/hooks-template.yaml" \
    ParameterKey=SchemaHandlerPackageS3URL,ParameterValue="https://<S3BucketName>.s3.us-west-2.amazonaws.com/mycompany-testing-mytesthook.zip"
  4. Check the progress of the stack deployment using the aws cloudformation describe-stack command. Move to the next section when the stack status is CREATE_COMPLETE.
    aws cloudformation describe-stacks --stack-name hooks-stack-set-stack
  5. If you navigate to the AWS CloudFormation Service’s StackSets section in the console, you can view the stack instances deployed to the accounts within the OU. Alternatively, you can execute the AWS CloudFormation list-stack-instances CLI command below to list the deployed stack instances:
    aws cloudformation list-stack-instances --stack-set-name MyTestHookStackSet

Testing the deployed hook

Deploy the following sample templates into any AWS account that is within the OU where the hooks was deployed and activated. Follow the steps in the Creating a stack on the AWS CloudFormation console. If using AWS CloudFormation CLI, follow the steps in the Creating a stack using the AWS Command Line Interface.

  1. Provision a non-compliant stack without server-side encryption using the following template:
    AWSTemplateFormatVersion: 2010-09-09
    Description: |
      This CloudFormation template provisions an S3 Bucket
    Resources:
      S3Bucket:
        Type: 'AWS::S3::Bucket'
        Properties: {}

    The stack deployment will not succeed and will give the following error message

    The following hook(s) failed: [MyCompany::Testing::MyTestHook] and the hook status reason as shown in the following screenshot:

    stack deployment failure due to hooks execution
    Diagram 3: S3 Bucket creation failure with hooks execution

  2. Provision a stack using the following template that has server-side encryption for the S3 Bucket.
    AWSTemplateFormatVersion: 2010-09-09
    Description: |
      This CloudFormation template provisions an encrypted S3 Bucket. **WARNING** This template creates an Amazon S3 bucket and a KMS key that you will be charged for. You will be billed for the AWS resources used if you create a stack from this template.
    Resources:
      EncryptedS3Bucket:
        Type: "AWS::S3::Bucket"
        Properties:
          BucketName: !Sub "encryptedbucket-${AWS::Region}-${AWS::AccountId}"
          BucketEncryption:
            ServerSideEncryptionConfiguration:
              - ServerSideEncryptionByDefault:
                  SSEAlgorithm: "aws:kms"
                  KMSMasterKeyID: !Ref EncryptionKey
                BucketKeyEnabled: true
      EncryptionKey:
        Type: "AWS::KMS::Key"
        DeletionPolicy: Retain
        UpdateReplacePolicy: Retain
        Properties:
          Description: KMS key used to encrypt the resource type artifacts
          EnableKeyRotation: true
          KeyPolicy:
            Version: 2012-10-17
            Statement:
              - Sid: Enable full access for owning account
                Effect: Allow
                Principal:
                  AWS: !Ref "AWS::AccountId"
                Action: "kms:*"
                Resource: "*"
    Outputs:
      EncryptedBucketName:
        Value: !Ref EncryptedS3Bucket

    The deployment will succeed as it will pass the hook validation with the following hook status reason as shown in the following screenshot:

    stack deployment pass due to hooks executionDiagram 4: S3 Bucket creation success with hooks execution

Updating the hooks package

To update the hooks package, follow the same steps described in the Hooks Development section to change the hook code accordingly. Then, execute the cfn submit --dry-run command to build and generate the hooks package file with the registering the type with the CloudFormation registry. Make sure to rename the zip file with a unique name compared to what was previously used. Otherwise, while updating the CloudFormation StackSets stack, it will not see any changes in the template and thus not deploy updates. The best practice is to use a CI/CD pipeline to manage the hook package. Typically, it is good to assign unique version numbers to the hooks packages so that CloudFormation stacks with the new changes get deployed.

Cleanup

Navigate to the AWS CloudFormation console on the Delegated Administrator account, and note down the Hooks package S3 bucket name and empty its contents. Refer to Emptying the Bucket for more information.

Delete the CloudFormation stacks in the following order:

  1. Test stack that failed
  2. Test stack that passed
  3. StackSets CloudFormation stack. This has a DeletionPolicy set to Retain, update the stack by removing the DeletionPolicy and then initiate a stack deletion via CloudFormation or physically delete the StackSet instances and StackSets from the Console or CLI by following: 1. Delete stack instances from your stack set 2. Delete a stack set
  4. Hooks asset CloudFormation stack

Refer to the following documentation to delete CloudFormation Stacks: Deleting a stack on the AWS CloudFormation console or Deleting a stack using AWS CLI.

Conclusion

Throughout this blog post, you have explored how AWS StackSets enable the scalable and centralized deployment of CloudFormation hooks across all accounts within an Organization Unit. By implementing hooks as reusable code templates, StackSets provide consistency benefits and slash the administrative labor associated with fragmented and manual installs. As organizations aim to fortify governance, compliance, and security through hooks, StackSets offer a turnkey mechanism to efficiently reach hundreds of accounts. By leveraging the described architecture of delegated StackSet administration and member account joining, organizations can implement a single hook across hundreds of accounts rather than manually enabling hooks per account. Centralizing your hook code-base within StackSets templates facilitates uniform adoption while also simplifying maintenance. Administrators can update hooks in one location instead of attempting fragmented, account-by-account changes. By enclosing new hooks within reusable StackSets templates, administrators benefit from infrastructure-as-code descriptiveness and version control instead of one-off scripts. Once configured, StackSets provide automated hook propagation without overhead. The delegated administrator merely needs to include target accounts through their Organization Unit alignment rather than handling individual permissions. New accounts added to the OU automatically receive hook deployments through the StackSet orchestration engine.

About the Author

kirankumar.jpeg

Kirankumar Chandrashekar is a Sr. Solutions Architect for Strategic Accounts at AWS. He focuses on leading customers in architecting DevOps, modernization using serverless, containers and container orchestration technologies like Docker, ECS, EKS to name a few. Kirankumar is passionate about DevOps, Infrastructure as Code, modernization and solving complex customer issues. He enjoys music, as well as cooking and traveling.

New – AWS Config Rules Now Support Proactive Compliance

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-aws-config-rules-now-support-proactive-compliance/

When operating a business, you have to find the right balance between speed and control for your cloud operations. On one side, you want to have the ability to quickly provision the cloud resources you need for your applications. At the same time, depending on your industry, you need to maintain compliance with regulatory, security, and operational best practices.

AWS Config provides rules, which you can run in detective mode to evaluate if the configuration settings of your AWS resources are compliant with your desired configuration settings. Today, we are extending AWS Config rules to support proactive mode so that they can be run at any time before provisioning and save time spent to implement custom pre-deployment validations.

When creating standard resource templates, platform teams can run AWS Config rules in proactive mode so that they can be tested to be compliant before being shared across your organization. When implementing a new service or a new functionality, development teams can run rules in proactive mode as part of their continuous integration and continuous delivery (CI/CD) pipeline to identify noncompliant resources.

You can also use AWS CloudFormation Guard in your deployment pipelines to check for compliance proactively and ensure that a consistent set of policies are applied both before and after resources are provisioned.

Let’s see how this works in practice.

Using Proactive Compliance with AWS Config
In the AWS Config console, I choose Rules in the navigation pane. In the rules table, I see the new Enabled evaluation mode column that specifies whether the rule is proactive or detective. Let’s set up my first rule.

Console screenshot.

I choose Add rule, and then I enter rds-storage in the AWS Managed Rules search box to find the rds-storage-encrypted rule. This rule checks whether storage encryption is enabled for your Amazon Relational Database Service (RDS) DB instances and can be added in proactive or detective evaluation mode. I choose Next.

Console screenshot.

In the Evaluation mode section, I turn on proactive evaluation. Now both the proactive and detective evaluation switches are enabled.

Console screenshot.

I leave all the other settings to their default values and choose Next. In the next step, I review the configuration and add the rule.

Console screenshot.

Now, I can use proactive compliance via the AWS Config API (including the AWS Command Line Interface (CLI) and AWS SDKs) or with CloudFormation Guard. In my CI/CD pipeline, I can use the AWS Config API to check the compliance of a resource before creating it. When deploying using AWS CloudFormation, I can set up a CloudFormation hook to proactively check my configuration before the actual deployment happens.

Let’s do an example using the AWS CLI. First, I call the StartProactiveEvaluationResponse API with in input the resource ID (for reference only), the resource type, and its configuration using the CloudFormation schema. For simplicity, in the database configuration, I only use the StorageEncrypted option and set it to true to pass the evaluation. I use an evaluation timeout of 60 seconds, which is more than enough for this rule.

aws configservice start-resource-evaluation --evaluation-mode PROACTIVE \
    --resource-details '{"ResourceId":"myDB",
                         "ResourceType":"AWS::RDS::DBInstance",
                         "ResourceConfiguration":"{\"StorageEncrypted\":true}",
                         "ResourceConfigurationSchemaType":"CFN_RESOURCE_SCHEMA"}' \
    --evaluation-timeout 60
{
    "ResourceEvaluationId": "be2a915a-540d-4595-ac7b-e105e39b7980-1847cb6320d"
}

I get back in output the ResourceEvaluationId that I use to check the evaluation status using the GetResourceEvaluationSummary API. In the beginning, the evaluation is IN_PROGRESS. It usually takes a few seconds to get a COMPLIANT or NON_COMPLIANT result.

aws configservice get-resource-evaluation-summary \
    --resource-evaluation-id be2a915a-540d-4595-ac7b-e105e39b7980-1847cb6320d
{
    "ResourceEvaluationId": "be2a915a-540d-4595-ac7b-e105e39b7980-1847cb6320d",
    "EvaluationMode": "PROACTIVE",
    "EvaluationStatus": {
        "Status": "SUCCEEDED"
    },
    "EvaluationStartTimestamp": "2022-11-15T19:13:46.029000+00:00",
    "Compliance": "COMPLIANT",
    "ResourceDetails": {
        "ResourceId": "myDB",
        "ResourceType": "AWS::RDS::DBInstance",
        "ResourceConfiguration": "{\"StorageEncrypted\":true}"
    }
}

As expected, the Amazon RDS configuration is compliant to the rds-storage-encrypted rule. If I repeat the previous steps with StorageEncrypted set to false, I get a noncompliant result.

If more than one rule is enabled for a resource type, all applicable rules are run in proactive mode for the resource evaluation. To find out individual rule-level compliance for the resource, I can call the GetComplianceDetailsByResource API:

aws configservice get-compliance-details-by-resource \
    --resource-evaluation-id be2a915a-540d-4595-ac7b-e105e39b7980-1847cb6320d
{
    "EvaluationResults": [
        {
            "EvaluationResultIdentifier": {
                "EvaluationResultQualifier": {
                    "ConfigRuleName": "rds-storage-encrypted",
                    "ResourceType": "AWS::RDS::DBInstance",
                    "ResourceId": "myDB",
                    "EvaluationMode": "PROACTIVE"
                },
                "OrderingTimestamp": "2022-11-15T19:14:42.588000+00:00",
                "ResourceEvaluationId": "be2a915a-540d-4595-ac7b-e105e39b7980-1847cb6320d"
            },
            "ComplianceType": "COMPLIANT",
            "ResultRecordedTime": "2022-11-15T19:14:55.588000+00:00",
            "ConfigRuleInvokedTime": "2022-11-15T19:14:42.588000+00:00"
        }
    ]
}

If, when looking at these details, your desired rule is not invoked, be sure to check that proactive mode is turned on.

Availability and Pricing
Proactive compliance will be available in all commercial AWS Regions where AWS Config is offered but it might take a few days to deploy this new capability across all these Regions. I’ll update this post when this deployment is complete. To see which AWS Config rules can be turned into proactive mode, see the Developer Guide.

You are charged based on the number of AWS Config rule evaluations recorded. A rule evaluation is recorded every time a resource is evaluated for compliance against an AWS Config rule. Rule evaluations can be run in detective mode and/or in proactive mode, if available. If you are running a rule in both detective mode and proactive mode, you will be charged for only the evaluations in detective mode. For more information, see AWS Config pricing.

With this new feature, you can use AWS Config to check your rules before provisioning and avoid implementing your own custom validations.

— Danilo

New for AWS Control Tower – Comprehensive Controls Management (Preview)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-for-aws-control-tower-comprehensive-controls-management-preview/

Today, customers in regulated industries face the challenge of defining and enforcing controls needed to meet compliance and security requirements while empowering engineers to make their design choices. In addition to addressing risk, reliability, performance, and resiliency requirements, organizations may also need to comply with frameworks and standards such as PCI DSS and NIST 800-53.

Building controls that account for service relationships and their dependencies is time-consuming and expensive. Sometimes customers restrict engineering access to AWS services and features until their cloud architects identify risks and implement their own controls.

To make that easier, today we are launching comprehensive controls management in AWS Control Tower. You can use it to apply managed preventative, detective, and proactive controls to accounts and organizational units (OUs) by service, control objective, or compliance framework. AWS Control Tower does the mapping between them on your behalf, saving time and effort.

With this new capability, you can now also use AWS Control Tower to turn on AWS Security Hub detective controls across all accounts in an OU. In this way, Security Hub controls are enabled in every AWS Region that AWS Control Tower governs.

Let’s see how this works in practice.

Using AWS Control Tower Comprehensive Controls Management
In the AWS Control Tower console, there is a new Controls library section. There, I choose All controls. There are now more than three hundred controls available. For each control, I see which AWS service it is related to, the control objective this control is part of, the implementation (such as AWS Config rule or AWS CloudFormation Guard rule), the behavior (preventive, detective, or proactive), and the frameworks it maps to (such as NIST 800-53 or PCI DSS).

Console screenshot.

In the Find controls search box, I look for a preventive control called CT.CLOUDFORMATION.PR.1. This control uses a service control policy (SCP) to protect controls that use CloudFormation hooks and is required by the control that I want to turn on next. Then, I choose Enable control.

Console screenshot.

Then, I select the OU for which I want to enable this control.

Console screenshot.

Now that I have set up this control, let’s see how controls are presented in the console in categories. I choose Categories in the navigation pane. There, I can browse controls grouped as Frameworks, Services, and Control objectives. By default, the Frameworks tab is selected.

Console screenshot.

I select a framework (for example, PCI DSS version 3.2.1) to see all the related controls and control objectives. To implement a control, I can select the control from the list and choose Enable control.

Console screenshot.

I can also manage controls by AWS service. When I select the Services tab, I see a list of AWS services and the related control objectives and controls.

Console screenshot.

I choose Amazon DynamoDB to see the controls that I can turn on for this service.

Console screenshot.

I select the Control objectives tab. When I need to assess a control objective, this is where I have access to the list of related controls to turn on.

Console screenshot.

I choose Encrypt data at rest to see and search through the available controls for that control objective. I can also check which services are covered in this specific case. I type RDS in the search bar to find the controls related to Amazon Relational Database Service (RDS) for this control objective.

I choose CT.RDS.PR.16 – Require an Amazon RDS database cluster to have encryption at rest configured and then Enable control.

Console screenshot.

I select the OU for which I want to enable the control for, and I proceed. All the AWS accounts in this organization’s OU will have this control enabled in all the Regions that AWS Control Tower governs.

Console screenshot.

After a few minutes, the AWS Control Tower setup is updated. Now, the accounts in this OU have proactive control CT.RDS.PR.16 turned on. When an account in this OU deploys a CloudFormation stack, any Amazon RDS database cluster has to have encryption at rest configured. Because this control is proactive, it’ll be checked by a CloudFormation hook before the deployment starts. This saves a lot of time compared to a detective control that would find the issue only when the CloudFormation deployment is in progress or has terminated. This also improves my security posture by preventing something that’s not allowed as opposed to reacting to it after the fact.

Availability and Pricing
Comprehensive controls management is available in preview today in all AWS Regions where AWS Control Tower is offered. These enhanced control capabilities reduce the time it takes you to vet AWS services from months or weeks to minutes. They help you use AWS by undertaking the heavy burden of defining, mapping, and managing the controls required to meet the most common control objectives and regulations.

There is no additional charge to use these new capabilities during the preview. However, when you set up AWS Control Tower, you will begin to incur costs for AWS services configured to set up your landing zone and mandatory controls. For more information, see AWS Control Tower pricing.

Simplify how you implement compliance and security requirements with AWS Control Tower.

— Danilo

New – Amazon Redshift Support in AWS Backup

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/new-amazon-redshift-support-in-aws-backup/

With Amazon Redshift, you can analyze data in the cloud at any scale. Amazon Redshift offers native data protection capabilities to protect your data using automatic and manual snapshots. This works great by itself, but when you’re using other AWS services, you have to configure more than one tool to manage your data protection policies.

To make this easier, I am happy to share that we added support for Amazon Redshift in AWS Backup. AWS Backup allows you to define a central backup policy to manage data protection of your applications and can now also protect your Amazon Redshift clusters. In this way, you have a consistent experience when managing data protection across all supported services. If you have a multi-account setup, the centralized policies in AWS Backup let you define your data protection policies across all your accounts within your AWS Organizations. To help you meet your regulatory compliance needs, AWS Backup now includes Amazon Redshift in its auditor-ready reports. You also have the option to use AWS Backup Vault Lock to have immutable backups and prevent malicious or inadvertent changes.

Let’s see how this works in practice.

Using AWS Backup with Amazon Redshift
The first step is to turn on the Redshift resource type for AWS Backup. In the AWS Backup console, I choose Settings in the navigation pane and then, in the Service opt-in section, Configure resources. There, I toggle the Redshift resource type on and choose Confirm.

Console screenshot.

Now, I can create or update a backup plan to include the backup of all, or some, of my Redshift clusters. In the backup plan, I can define how often these backups should be taken and for how long they should be kept. For example, I can have daily backups with one week of retention, weekly backups with one month of retention, and monthly backups with one year of retention.

I can also create on-demand backups. Let’s see this with more details. I choose Protected resources in the navigation pane and then Create on-demand backup.

I select Redshift in the Resource type dropdown. In the Cluster identifier, I select one of my clusters. For this workload, I need two weeks of retention. Then, I choose Create on-demand backup.

Console screenshot.

My data warehouse is not huge, so after a few minutes, the backup job has completed.

Console screenshot.

I now see my Redshift cluster in the list of the resources protected by AWS Backup.

Console screenshot.

In the Protected resources list, I choose the Redshift cluster to see the list of the available recovery points.

Console screenshot.

When I choose one of the recovery points, I have the option to restore the full data warehouse or just a table into a new Redshift cluster.

Console screenshot.

I now have the possibility to edit the cluster and database configuration, including security and networking settings. I just update the cluster identifier, otherwise the restore would fail because it must be unique. Then, I choose Restore backup to start the restore job.

After some time, the restore job has completed, and I see the old and the new clusters in the Amazon Redshift console. Using AWS Backup gives me a simple centralized way to manage data protection for Redshift clusters as well as many other resources in my AWS accounts.

Console screenshot.

Availability and Pricing
Amazon Redshift support in AWS Backup is available today in the AWS Regions where both AWS Backup and Amazon Redshift are offered, with the exception of the Regions based in China. You can use this capability via the AWS Management Console, AWS Command Line Interface (CLI), and AWS SDKs.

There is no additional cost for using AWS Backup compared to the native snapshot capability of Amazon Redshift. Your overall costs depend on the amount of storage and retention you need. For more information, see AWS Backup pricing.

— Danilo