Tag Archives: AWS Security Hub

We invited a direct competitor into Security Hub Extended. Here’s why.

Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/we-invited-a-direct-competitor-into-security-hub-extended-heres-why/

When customers keep pointing you to a solution that overlaps with parts of your own offering, you have a choice to make. This post is about the choice we made with Upwind, and why we’d make it again.

AWS Security Hub Extended exists because customers told us what was working for them in enterprise security and asked us to simplify adoption and integration. Upwind was one of the solutions customers kept naming, so we brought them in. Upwind didn’t only agree to participate, they committed fully to integration. They brought their full solution portfolio into Extended with aggressive pay-as-you-go pricing from day one. They got their field organization fully aligned on joint deal flow and have driven more customer activity and closed deals through Security Hub Extended than any other partner in the program.

Giving customers choice, even when it overlaps

Multiple best-of-breed options in cloud security—including one that overlaps with our own capabilities—are straightforward when you start with what customers need. Some will choose Security Hub Essentials for cloud security posture management and vulnerability scanning. Some will choose Upwind for runtime-first protection. Some will run both and get stronger outcomes from the combination. The customer decides, not us. That principle applies to every partner in Security Hub Extended. We listen to what’s working, and we simplify adoption through the same AWS relationship customers already have.

“Our customers run on AWS, and Security Hub is where their security operations live,” said Amiram Shachar, Co-Founder and CEO of Upwind. “Being inside Security Hub means customers get Upwind’s cloud workload protection with the same billing, the same support path, and the same operational model they already know. We’re here because it’s a better outcome for the customers we share.”

Who is Upwind?

Upwind is a cloud security company trusted by Siemens, Peloton, Roku, Wix, Nextdoor, and Nubank. Fast Company named them one of the Most Innovative Companies of 2026.

What makes them different is runtime. Most cloud security solutions scan configurations periodically and report what could be a risk based on static posture. Upwind deploys an eBPF-based sensor directly in the Linux kernel that sees what workloads are doing in real time, including process behavior, network connections, API calls, and container interactions. All observed continuously. That means Upwind can tell you not only what could theoretically be exploited, but what is actively at risk right now. That distinction cuts alert noise dramatically and lets security teams focus on what genuinely matters.

Better together. Not only with AWS, but with each other

Now extend that to the rest of your security stack. If you’re already running other Security Hub Extended solutions, they work together without you building the integrations.

A customer running Chainguard for supply chain security, Upwind for runtime protection, and Splunk for security operations gets a connected experience. Chainguard helps ensure clean, malware-resistant dependencies at build time. Upwind validates workload behavior at runtime and enriches those findings with real-time context. Everything flows into Splunk through Security Hub for unified triage. One experience, one bill, no custom integration work. The security team sees the full lifecycle from build to production without stitching tools together.

That same pattern applies with 7AI, where AI-driven automation can triage and investigate Upwind’s runtime events alongside endpoint, identity, and network signals, all without manual pipeline work.

This is the multi-way partnership that Security Hub Extended was designed to enable. These solutions aren’t only easier to buy together, they’re building toward each other. The findings flow into Security Hub in OCSF (Open Cybersecurity Schema Framework), get correlated and prioritized together, and route to the downstream tools your team already uses. Your security stack gets stronger as a whole, not only solution by solution.

How it works commercially

This isn’t a paper partnership. We’re closing multi-million dollar deals together through Security Hub Extended. Upwind has engaged faster than any other partner in the program, bringing their own customer opportunities and joining AWS-originated deals to close them jointly. One enterprise customer recently replaced their incumbent CNAPP with Upwind through a Security Hub Extended Private Offer. The deciding factors were runtime visibility that their previous solution couldn’t deliver and a single predictable commercial model that replaced complex per-module pricing across multiple vendors. The commercial model has momentum, and it’s because Upwind invested not only in signing an agreement but in the engineering and go-to-market work that makes joint success real.

Upwind is available through Security Hub Extended with pay-as-you-go pricing, one AWS bill, and no required long-term commitment. For enterprises that prefer committed-pricing agreements, Security Hub Extended Private Offers are also available with deeper discounts and the ability to aggregate spend across partners. You choose the path that fits how you buy. If you’re already running Security Hub for posture management and vulnerability scanning, adding Upwind gives you runtime visibility alongside what you already see. No new tooling to stand up, no new workflow to learn. It shows up in your existing prioritized view of risk.

What Upwind is building next

Upwind continues to expand. AI workload protection that monitors model behavior and agent tool calls at runtime. Windows Server VM coverage across AWS, Azure, and GCP. Deeper integration with the Security Hub correlation engine so runtime context enriches attack-path intelligence automatically. The partnership deepens as both sides invest.

“We believe runtime context and AWS-native signals together produce stronger outcomes than either alone,” said Amiram Shachar, Co-Founder and CEO of Upwind. “As Security Hub deepens its correlation and Upwind extends its runtime fabric, customers who use both will have a view of risk that no single solution can replicate. That’s the future we’re building toward together.”

What this means for you

Security Hub Extended exists to give you access to the solutions your peers are already succeeding with through the AWS relationship you already have. Upwind is what that philosophy looks like when applied to a category where AWS has an existing offering. We listened to customers, saw what was working for them, and made it available with the same commercial model as everything else.

Enable Upwind through the AWS Security Hub console. Pay-as-you-go. No commitment required. If you want to understand what consolidation looks like with Security Hub Extended, talk to your AWS account team.

We’re just getting started, but the momentum is real.

If you have feedback about this post, submit comments in the Comments section below.


Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.

Detecting multi-stage attacks on AWS: A guide to cross-service signal correlation

Post Syndicated from Nisha Kashyap original https://aws.amazon.com/blogs/security/detecting-multi-stage-attacks-on-aws-a-guide-to-cross-service-signal-correlation/

A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.

Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.

This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.

Start with AWS detection services

Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.

Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.

GuardDuty correlates multi-stage attacks for you

Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.

The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.

GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.

Add your business context

Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.

Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).

Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).

A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.

The attack chain mapped to AWS services

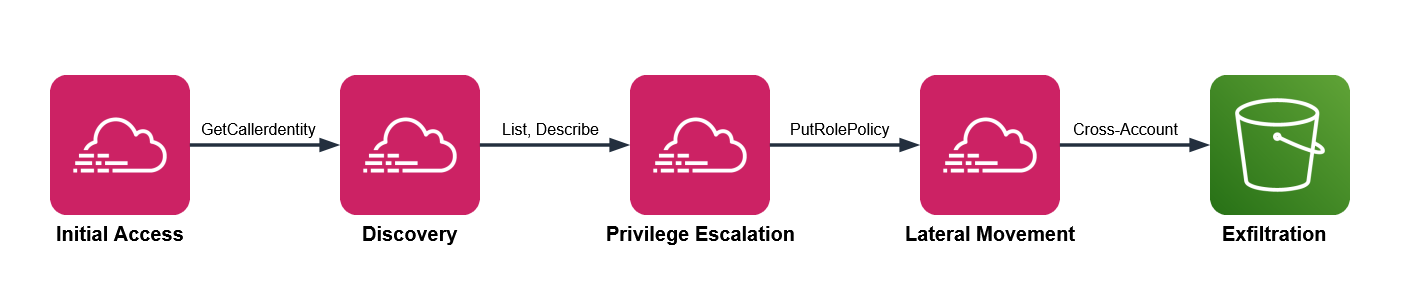
Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.

  • Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
  • Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
  • Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
  • Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
  • Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.

Figure 1 shows the five attack phases mapped to the AWS log source that records each one.

Figure 1: Attack chain mapped to AWS services

Figure 1: Attack chain mapped to AWS services

GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.

Pattern one: Sensitive data access by an unexpected principal

Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.

Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.

CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.

This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.

fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc

The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.

To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.

fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc

The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.

Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.

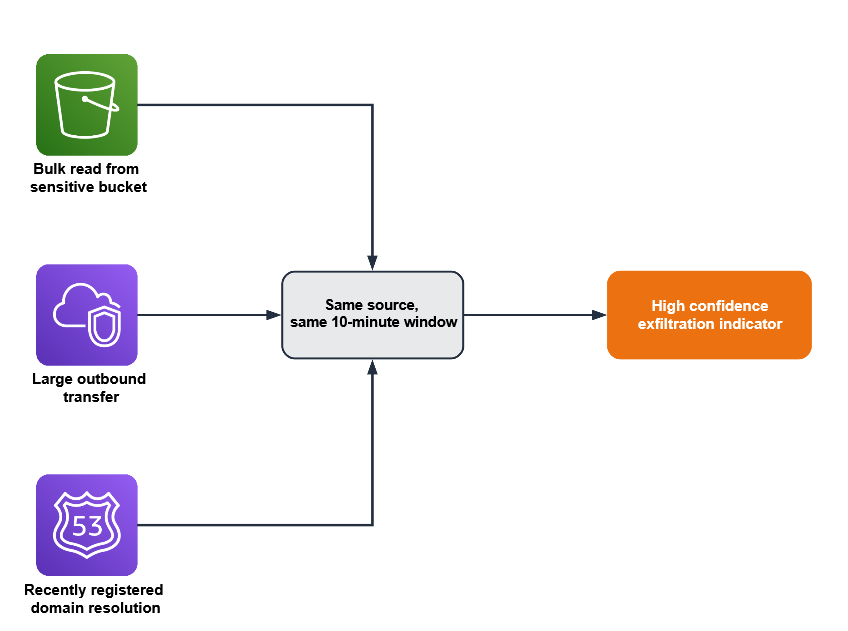
Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.

Figure 2: Three signals converging within a single time window to indicate exfiltration

Figure 2: Three signals converging within a single time window to indicate exfiltration

Pattern two: A role chain that crosses your access policy

Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.

This pattern needs three conditions:

  • CloudTrail shows several AssumeRole calls from the same source inside a short window
  • The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
  • The starting identity isn’t one your policy expects to run that chain

In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.

fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc

Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.

Pattern three: An encryption key used outside its owning workload

Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.

This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.

Two conditions indicate misuse:

  • CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
  • The calling principal isn’t the role that owns that workload

Against your CloudTrail log group, run this query to list the principals that called a specific key.

fields @timestamp, userIdentity.arn, eventName
| filter eventSource = "kms.amazonaws.com"
| filter eventName in ["Decrypt", "GenerateDataKey", "Encrypt"]
| filter resources.0.ARN = "arn:aws:kms:region:account-id:key/your-key-id"
| stats count(*) as keyUses by userIdentity.arn, eventName
| sort keyUses desc

Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.

Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.

Pattern four: A privileged action outside your change window

Start with the query, then read what it means.

fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc

Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.

Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.

Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.

Build your first correlation rule

The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.

Prerequisites

These prerequisites feed the queries in this walkthrough. Confirm each one before you start:

  • A CloudTrail trail logging management events to a CloudWatch Logs log group
  • CloudTrail data events enabled for your sensitive S3 buckets
  • GuardDuty enabled, with its protection plans and Extended Threat Detection
  • VPC Flow Logs on for your production VPCs
  • Amazon Route 53 Resolver query logging on

CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.

Step 1: Record the bucket and its expected readers

Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).

{
  "customer-records-prod": [
    "arn:aws:iam::123456789012:role/AnalyticsPipeline",
    "arn:aws:iam::123456789012:role/ComplianceAudit"
  ],
  "financial-data-archive": [
    "arn:aws:iam::123456789012:role/FinanceReporting"
  ]
}

This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.

Step 2: Baseline before you set a threshold

Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.

Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.

Step 3: Run the access query

In the CloudWatch console:

  1. Choose Logs, then choose Logs Insights.
  2. In the Select log group(s) dropdown, select your CloudTrail log group.
  3. Set the time range to 3h (the last three hours).
  4. In the query editor, paste the pattern one query.
  5. Replace your-sensitive-bucket with your bucket name.
  6. Choose Run query.
  7. Review the principals in the results table.
  8. Compare each principal against your expected reader list from step 1, and flag any that are not on it.

Each result includes a principal that step 4 translates into an IP address.

Step 4: Correlate with network activity

CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.

For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.

aws ec2 describe-instances \
  --instance-ids i-1234567890abcdef0 \
  --query "Reservations[0].Instances[0].PrivateIpAddress" \
  --output text

Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.

Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.

Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.

Step 5: Automate the check

Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.

To create the notification channel

  1. Open the Amazon Simple Notification Service (Amazon SNS) console. Amazon SNS is a managed messaging service that delivers notifications to subscribers.
  2. In the navigation pane, choose Topics.
  3. Choose Create topic.
  4. For Type, select Standard.
  5. For Name, enter security-correlation-alerts.
  6. Choose Create topic.
  7. Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
  8. Choose Create subscription.
  9. For Protocol, select Email.
  10. For Endpoint, enter your email address or incident management endpoint.
  11. Choose Create subscription, then confirm the subscription from the email AWS sends.

To create the EventBridge Scheduler execution role

The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.

1. Create a trust policy file named scheduler-trust-policy.json.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": { "Service": "scheduler.amazonaws.com" },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "aws:SourceAccount": "ACCOUNT-ID"
        },
        "ArnLike": {
          "aws:SourceArn": "arn:aws:scheduler:REGION:ACCOUNT-ID:schedule/*/s3-access-correlation-hourly"
        }
      }
    }
  ]
}

2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.

aws iam create-role \
  --role-name EventBridgeSchedulerRole \
  --assume-role-policy-document file://scheduler-trust-policy.json

aws iam put-role-policy \
  --role-name EventBridgeSchedulerRole \
  --policy-name LambdaInvokePolicy \
  --policy-document '{
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "Allow",
        "Action": "lambda:InvokeFunction",
        "Resource": "arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction"
      }
    ]
  }'

When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.

To deploy the correlation function

  1. Open the Lambda console.
  2. Choose Create function.
  3. For Function name, enter CorrelationFunction.
  4. For Runtime, select the latest Python runtime.
  5. Choose Create function.
  6. On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")

  1. On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
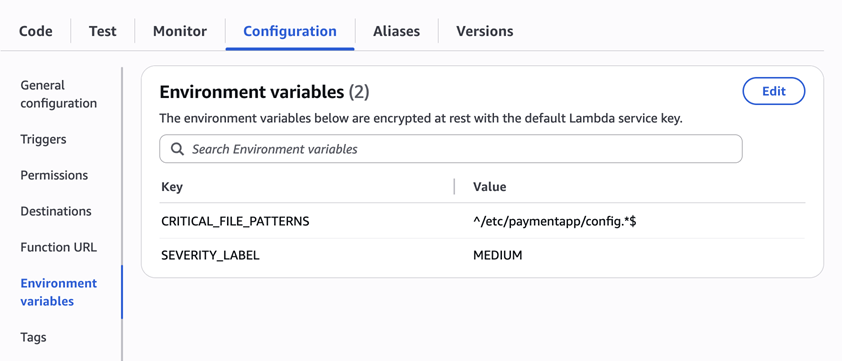
  2. On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
  3. On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["logs:StartQuery", "logs:GetQueryResults"],
      "Resource": [
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:aws-cloudtrail-logs-my-trail:*",
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:vpc-flow-logs:*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": "ec2:DescribeInstances",
      "Resource": "*"
    },
    {
      "Effect": "Allow",
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:REGION:ACCOUNT-ID:security-correlation-alerts"
    }
  ]
}

Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.

To schedule automated runs

Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.

aws scheduler create-schedule \
  --name s3-access-correlation-hourly \
  --schedule-expression "rate(1 hour)" \
  --target "Arn=arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction,RoleArn=arn:aws:iam::ACCOUNT-ID:role/EventBridgeSchedulerRole" \
  --flexible-time-window "Mode=OFF"

Step 6: Add enrichment context (optional)

Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.

import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None

Inside the handler’s loop, after you resolve ip, append the location to the alert.

            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )

Step 7: Scale to additional patterns and accounts

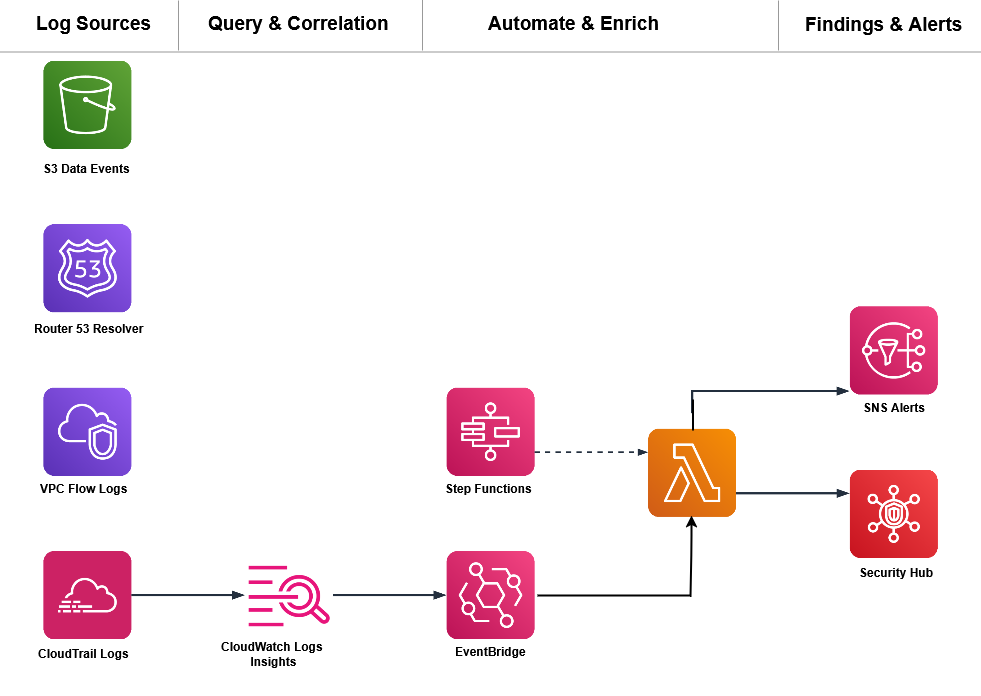
As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.

Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.

Figure 3: A correlation pipeline built on AWS services

Figure 3: A correlation pipeline built on AWS services

Conclusion

You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.

  • Identity is your primary correlation key: Track the same principal across services.
  • Time windows matter, but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
  • Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
  • Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.

GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.

Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.

Further reading
 

Nisha Kashyap

Nisha Kashyap

Nisha Kashyap is a Senior Support Security Engineer at AWS. She works on threat detection and security operations, helping customers investigate security events and build detection that connects signals across AWS services and reflects their own environment.

Security Hub Extended adds Supply Chain Security as its tenth category

Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/security-hub-extended-adds-supply-chain-security-as-its-tenth-category/

Since February, we’ve grown AWS Security Hub Extended from 14 curated partners across 9 categories to 23 partners across 10. At Black Hat this month, 14 of those partners were at the Amazon Web Services (AWS) booth demoing live. Four of those partners delivered theater talks and ten were featured on SecurityLive streaming. We hosted a partner reception that brought our leadership together with partner executives to plan what comes next. These are companies investing real engineering and real go-to-market (GTM) alongside us, and increasingly with each other, because the model resonates with the customers they’re talking to every day. The most common question we heard at the booth was when Supply Chain Security was coming.

It’s here. And that’s the thing I want to spend the most time on today, because it’s the category customers keep asking us about.

Supply Chain Security: The category customers have been asking for

Software supply chain risk has moved from a security-team concern to a board-level conversation. SolarWinds showed what happens when a build system is compromised. Log4j showed what a single transitive dependency vulnerability can do at global scale. The xz utils backdoor showed the patience of a maintainer-compromise attack executed over years. Each demonstrated a different dimension of the same problem, and the pace is accelerating. Attackers know that a fast way into an enterprise is through the open source packages that enterprise unknowingly trust.

Every customer I talked to at Black Hat had this on their risk register. Most still hadn’t operationalized a solution, because doing so meant a standalone deployment, a new contract, a new console, and integration work their security team couldn’t prioritize. That’s the friction we aim to remove.

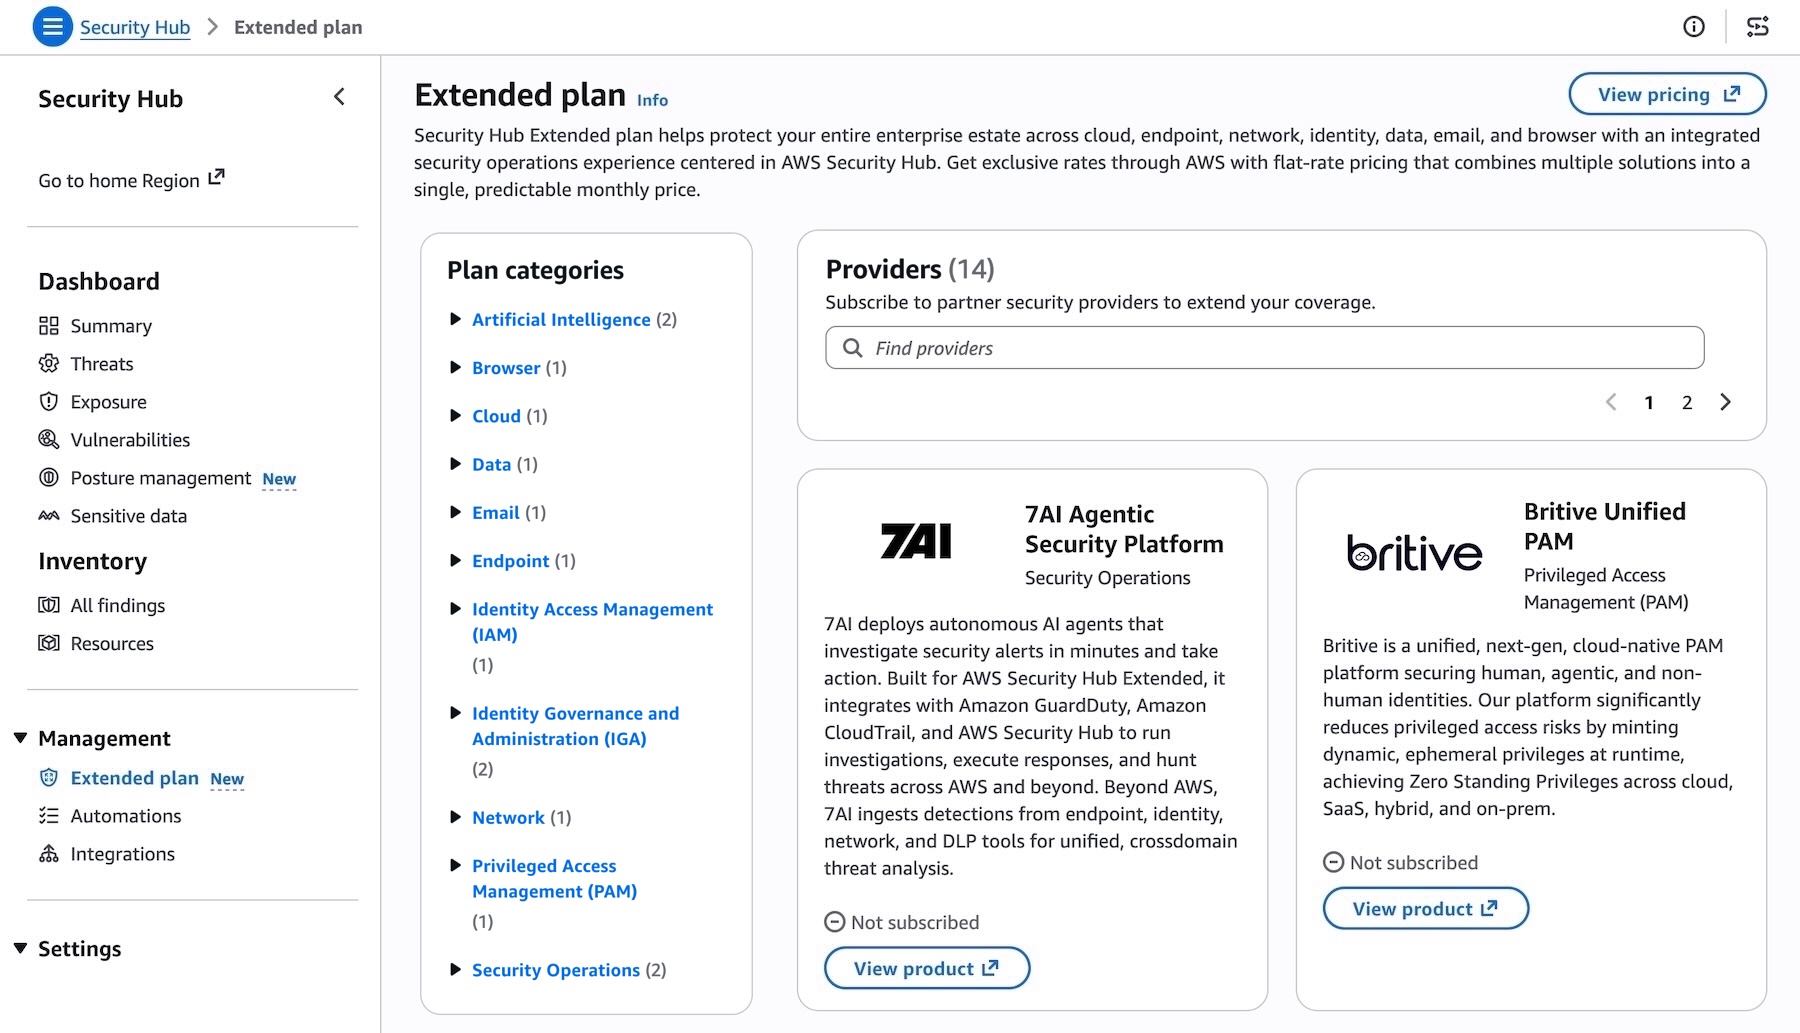
Security Hub Extended now offers Supply Chain Security with Chainguard and Socket as the curated partners. Supply Chain Security uses the same model as everything else in Extended. Every offering has pay-as-you-go pricing, one bill, no required long-term commitment. For enterprises that prefer to continue using the procurement process they always have, Security Hub Extended Private Offers are also available. These are committed term agreements with deeper discounts, the ability to aggregate spend across partners on a single AWS bill, and both monthly and annual payment options throughout the term. You pick the path that fits how you buy.

What Chainguard does

Chainguard gives you open source dependencies rebuilt from source in a hardened, verified build process, so what enters your environment is malware-resistant and provenance-backed. Their research shows that rebuilding from source would have stopped 98% of known malicious packages from ever reaching production. If you can’t verify the source, it never appears in the Chainguard repository. That’s the filter between the public registry and your developers.

What Socket does

Socket analyzes the actual behavior of open source packages to block malicious dependencies at the time of install. Not after a Common Vulnerability and Exposures (CVE) is published days or weeks later. At the moment the package tries to land in your environment, Socket flags it based on what it does, not what a database says about it. Its reachability analysis then tells you which vulnerabilities are exploitable from your code instead of drowning your team in noise. You pay for the distinct packages you check, not for how often your builds run.

Why they work together

Together, Chainguard and Socket cover the two questions that matter:

  • Can I trust what I’m pulling in?
  • Can I stop malicious components before they get built into my applications?

Chainguard helps secure the foundation your code is built on. Socket secures the packages you pull into it. Both help protect your software supply chain regardless of where you deploy—across clouds or on-premises. Activate both through Security Hub Extended and their findings flow into Security Hub in OCSF (Open Cybersecurity Schema Framework) alongside everything else, so a supply chain risk is correlated and prioritized next to your endpoint, identity, and cloud signals. From there, it routes out to the downstream tools you’ve already integrated, so it fits the pipeline your builders run today.

23 partners, 10 categories. Built on what customers asked for

Every partner in Security Hub Extended is here because customers told us they needed that capability and that specific solution was already working for them. We add categories because the threat landscape evolves, and we add partners because customers point us to who’s solving those problems well. The goal is straightforward: Simplify adopting the security solutions your peers are already succeeding with, through the AWS relationship you already have.

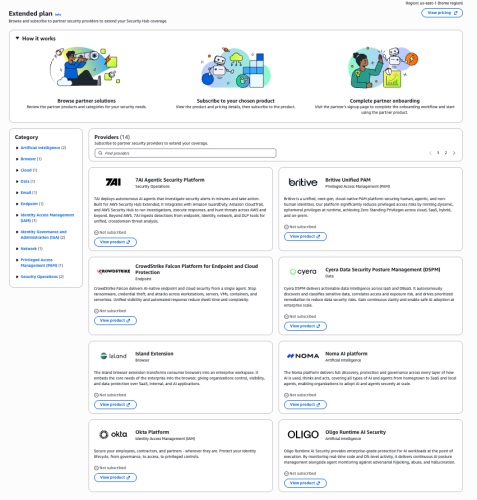
The full set today spans endpoint, identity, email, network, data, browser, cloud, AI, security operations, and now supply chain. The 23 curated partners are 7AI, Britive, Chainguard, CrowdStrike, Cyera, Island, LayerX, Native Security, Noma, Okta, Oligo, Opti, Palo Alto Networks, Proofpoint, SailPoint, SentinelOne, Socket, Splunk, Sublime, Upwind, Varonis, Zenity, and Zscaler.

Our focus now is deepening integrations and reducing activation friction so these solutions work together, not in isolation. That’s where the real value compounds.

What we’re building next

Everything I’ve described so far is the commercial model working: Customers buying best-of-breed security through one AWS relationship with the flexibility they expect. But the bigger vision is the integration layer that makes these tools genuinely better together, not just easier to buy together.

The integration we’re most focused on is cross-partner correlation, turning signals from an endpoint solution, an identity solution, and a cloud solution into one exposure and one attack path instead of three disconnected alerts. Right alongside that, we’re dramatically reducing the activation, deployment, and integration friction so customers go from subscribing to seeing value in hours rather than weeks. Both efforts enable the curated solutions you already trust to deliver stronger outcomes together than they do apart.

That’s the build we’re accelerating with our partners now, and you’ll hear more leading into re:Invent.

Explore what’s available

If you’re running open source in production and don’t yet have supply chain visibility, start there. Activate Chainguard and Socket through the Security Hub console today. If you’re managing multiple security vendor relationships and want to understand what consolidation looks like with Security Hub Extended, talk to your AWS account team. Pricing for every partner is published on our pricing page, no sales call required. And if you’re already using Security Hub for posture management and threat detection, the Extended plan is available in the same console you already use.

We’re just getting started.

If you have feedback about this post, submit comments in the Comments section below.


Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.

Security Hub adds AI workload protection and multicloud support for Microsoft Azure

Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/security-hub-adds-ai-workload-protection-and-multicloud-support-for-microsoft-azure/

Security Hub is our foundation for full-stack enterprise security across clouds. It centralizes your security operations and turns raw signals into prioritized insights, so your team spends its time managing real risk instead of stitching tools together. Today that foundation grows in two directions our customers asked for most. We are adding purpose-built protection for AI workloads, and security monitoring for Microsoft Azure. Both are steps toward a bigger idea, that your best security tools should get smarter by working together.

These expansions came directly from customers, and they reflect where security is heading, not where it has been. The old promise of security tooling was a place to collect everything in one view. Collecting findings was never the hard part. The hard part is understanding them, connecting them, and acting before an attacker does, and doing it at the speed attacks now move. The programs that win from here will be the ones that see across their whole estate and respond fast, not the ones with the most dashboards. That is what we are building toward, and these launches are steps on that path.

Multicloud security management for Microsoft Azure

Customers across industries have made Security Hub a core part of how they run security on AWS. Most of them have run in more than one cloud for years, and they have been clear with us that they want Security Hub to also cover the rest of their estate. Today we do that for Microsoft Azure, with more clouds following quickly.

Security Hub now discovers Azure Virtual Machines, container images, Function Apps, and identities, then evaluates them for misconfigurations, internet exposure, and software vulnerabilities, with posture checks against the CIS Microsoft Azure Foundations Benchmark™. Azure findings are prioritized next to your AWS findings using the same finding format, automation, and response workflows, so your team works from one understanding of risk across your entire estate. Azure resources are priced at the same rates as equivalent AWS resources with no additional fees, and there’s an independent 30-day free trial. To learn more, see the What’s New post.
This is not actually our first move beyond AWS. Earlier this year we introduced Security Hub Extended, bringing best-in-class partner solutions across nine security categories into the same experience you already use. Those partner solutions protect endpoints, identities, email, browsers, and data wherever they run, across any cloud, on-premises, and everywhere your enterprise operates. Extended was already our first multicloud and multi-workload step. Today we broaden what our own native capabilities cover, and the two lines of work now advance together.

Protecting AI workloads

Every customer I talk to is building with AI. Generative AI on Amazon Bedrock, model training on SageMaker, agents orchestrating workflows through AgentCore. These workloads are reaching production faster than most security programs can keep up, and teams often don’t yet have the tools to monitor model invocations, track agent behavior, or even know what AI assets exist across the organization. One security leader told me his team only caught a compromised service account, one that had been invoking a foundation model thousands of times, because finance questioned the bill. They found a security incident through an accounting review. The visibility gap is real, and it is already expensive.

This summer we start closing it with three launches. Two are GuardDuty capabilities for threat detection and investigation, and a third is a new Security Hub AI inventory.

GuardDuty AI Protection (generally available)

Amazon GuardDuty AI Protection delivers threat detection purpose-built for Bedrock and SageMaker. It detects anomalous model invocations, cost harvesting attacks where adversaries abuse stolen credentials to run inference at your expense, and prompt injection attempts through integration with Bedrock Guardrails.

Cost harvesting is accelerating. When credentials are compromised, attackers increasingly use them to invoke foundation models. Inference is expensive, demand is high, and stolen access converts straight to value without deploying any infrastructure. GuardDuty analyzes CloudTrail data events, learns what normal invocation looks like at scale, and flags the deviations that signal compromise or abuse. This is detection that only works at AWS scale, because you have to see the signal across millions of workloads to know what normal is. GuardDuty AI Protection is now available to all GuardDuty customers with a 30-day free trial.

GuardDuty AI-powered investigations (preview)

AI-powered investigations take on the manual investigation work that drives alert fatigue and slows response. The capability automatically analyzes GuardDuty findings and the accounts around them to separate true threats from benign activity.

It examines finding context, related activity from the last 90 days, affected resources, and threat indicators, using knowledge graphs and threat intelligence to complete in minutes what used to take hours. Each investigation returns a disposition assessment with confidence scoring, MITRE ATT&CK® classification, supporting evidence, and clear recommendations to suppress, contain, or remediate. Your team focuses on genuine threats, whether across a single account or an entire AWS Organization, and mean time to resolution drops. GuardDuty AI-powered investigations is available in preview in 10 AWS Regions.

Security Hub AI inventory (generally available)

You can’t secure what you don’t know exists. Security Hub now provides an AI inventory, a continuously updated, organization-wide view of your AI assets and their security posture. As teams deploy models, agents, and pipelines, security often can’t see what’s running, and without connecting those assets to active threats and misconfigurations, it’s difficult to know what to secure first.

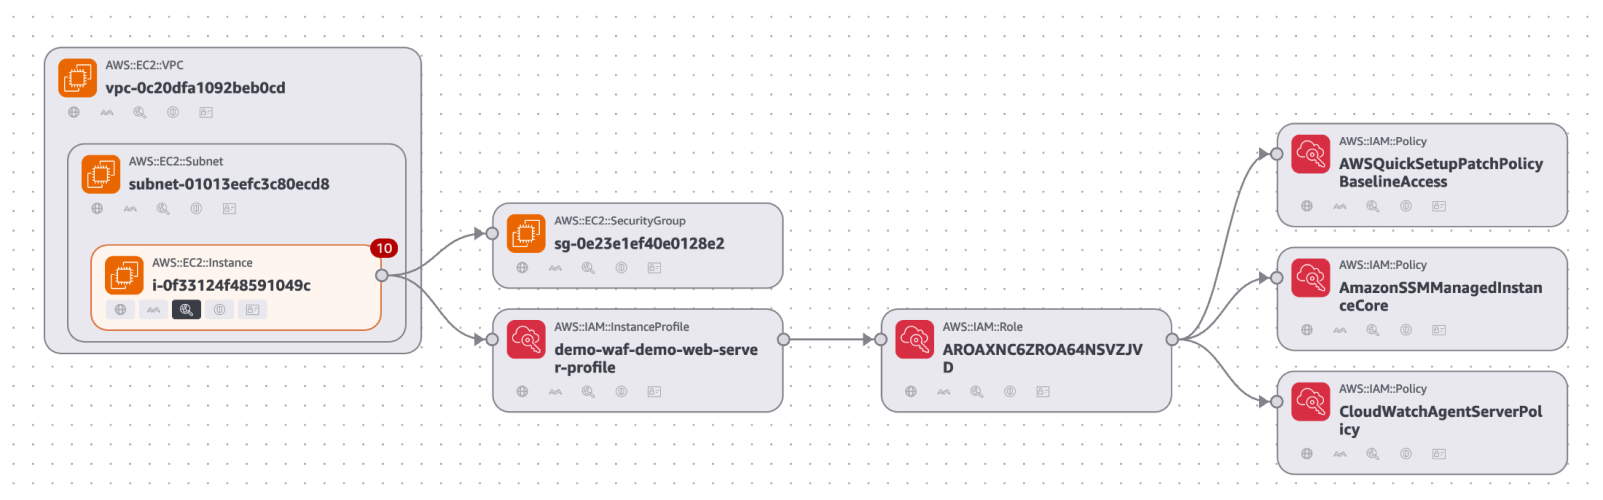
Security Hub AI inventory discovers and catalogs AI workloads across your AWS environment two ways. For managed services, it inventories AWS Config resources across Bedrock, SageMaker, and AgentCore. For self-hosted and external workloads, it finds models running on EC2, ECS, and EKS through runtime analysis, and identifies the external model endpoints your workloads make calls to. It maps each asset to the infrastructure beneath it, including compute, networking, IAM roles, and data stores, and correlates it with security signals such as GuardDuty findings. So when GuardDuty AI Protection flags an anomalous invocation, AI inventory immediately shows you which infrastructure is involved, what’s connected to it, and where it belongs in your priority order.

AI assets multiply fast. A developer spins up a Bedrock agent for a proof of concept. A data science team stands up a SageMaker endpoint for internal testing. Another team wires in an external model API through a Lambda function. Multiply that across hundreds or thousands of accounts and you can quickly lose track. AI inventory gives you that view across every account in your organization, available in your Security Hub Essentials plan at no additional cost.

A different approach to full-stack security

These launches share something worth pausing on. You didn’t procure AI protection as a separate product, and you won’t stand up separate operations for Azure. You add them to the Security Hub you already run, and they show up in your prioritized view of risk. That same idea is what Security Hub Extended extends to the rest of the security estate.

Security Hub Extended now has 21 curated partners across nine categories: 7AIBritiveCrowdStrike, Idira (CyberArk), CyeraIsland, LayerX, Native Security, NomaOktaOligoOptiProofpointSailPoint, SentinelOneSplunkSublime, Upwind, Varonis, Zenity, and Zscaler. These are best-in-class solutions across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. None of them are here by default. Each one earned its place by committing to a shared view of where enterprise security is going, and by investing alongside us to build it. Curation is the point. A recommendation only means something if it can be turned down.

The commercial benefits of Extended are real today. Pay-as-you-go pricing, a single AWS bill, EDP eligibility, and no long-term commitments. But the work we’re most excited about goes further, and it’s not about procurement at all. Findings from every participating solution are emitted in the Open Cybersecurity Schema Framework (OCSF) and aggregated in Security Hub, and we’re building toward a single correlation across all of them, so a signal from an endpoint solution, an identity solution, and a cloud solution combine into one exposure and one attack path instead of three disconnected alerts. We’re working to reduce the deployment and onboarding effort between subscribing and seeing value. And we’re building the exchange that lets partner findings enrich each other, so the best-in-class tools you already trust become more than the sum of their parts. That is the differentiated future we’re investing in, and we’re building it in the open, guided by what customers ask for next. To learn more about Extended, see the What’s New post.

Accelerating forward

Step back and the shape of it is clear. Security Hub reaches across cloud providers, starting with Azure and expanding from there. It reaches across workload types with purpose-built AI protection and inventory. And it reaches across security categories through Extended and its curated partners. What began as a way to bring order to AWS security findings has become how more enterprises run full-stack security.

Detection and visibility are the foundation. What we build on top of them is a security experience that connects signals across every source you trust and helps you respond faster. It’s still Day 1, and Security Hub will keep extending as your environment, and the threats you face, continue to change.

If you have feedback about this post, submit comments in the Comments section below.


Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.

AWS Weekly Roundup: AWS Builder Center at 1 year, Network Scanning in Security Hub, Loom for AWS, and more (July 13, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-builder-center-at-one-year-network-scanning-in-security-hub-loom-for-aws-and-more-july-13-2026/

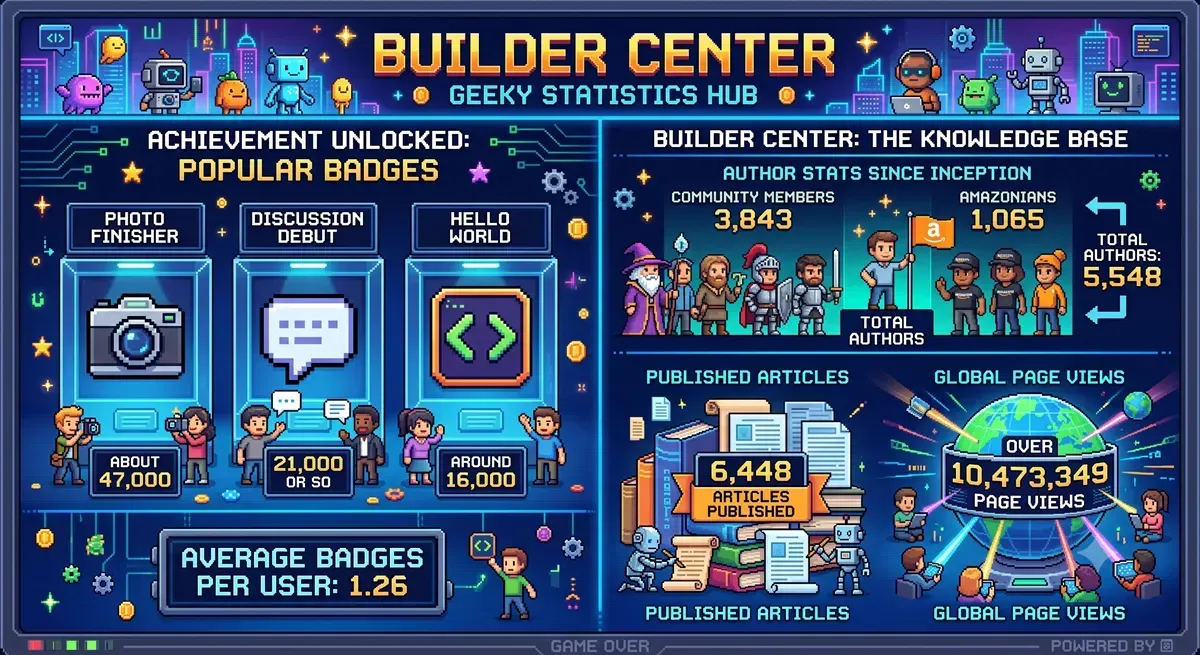
AWS Builder Center turned one year old last week. Launched on July 9, 2025, the platform has grown from a community hub with Wishlist voting, community profiles, and a toolbox into a full ecosystem with sandbox environments, workshops, Spaces, and a Builders’ Library. To mark the anniversary, Rick Suttles published a full feature timeline covering everything shipped over the past year: AWS Capabilities by Region (1,500+ services across 37 Regions), Spaces for community-created groups, workshops with category and complexity filters, badges and streaks, article series, view counts, saved items, student status, availability notifications, sign-in with GitHub and Amazon, and sandbox environments.

Jeff Barr published a retrospective summarizing Builder Center’s first year. Since launch, 5,548 authors have published 6,448 articles with more than 10.4 million page views combined. Builders have earned 99,226 badges since the badge system launched in March 2026. Community members have submitted 565 wishes, 10 of which have shipped with another 20 on the near-term roadmap.

The top community article Building an AWS Study Buddy with MCP + Strands Agents SDK by Dineshraj Dhanapathy reached 50,000+ views. Chris Miller’s Migrating an EOL Linux Server to AWS in 8 Hours with Kiro followed at 45,000+, and Yash Aggarwal’s AIdeas: NeuroVoice – Multimodal AI for Early Screening of Neurological Diseases article reached 38,000+.

The week’s headline addition is Sandbox Environments by Rick Suttles. Sandboxes give you a free, pre-provisioned AWS account to complete a workshop exercise. Each environment is active for 8 hours, after which the account and all its resources are automatically de-provisioned. You can have one active sandbox at a time and request one per week. No personal AWS account, credit card, or manual cleanup required.

Last week’s launches
Here’s what else happened this week.

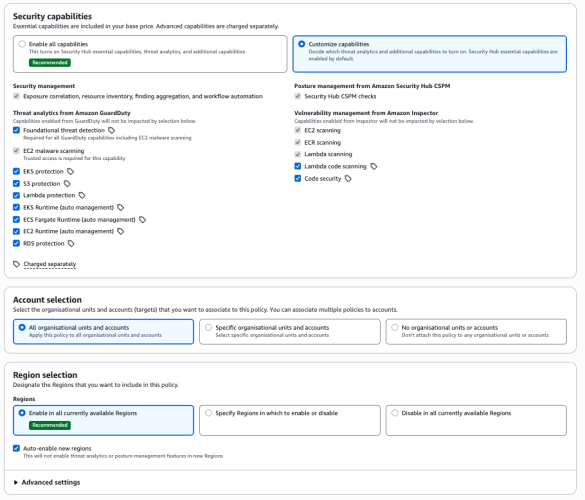
  • AWS Security Hub introduces Network Scanning – Security Hub introduced Network Scanning, a capability that identifies resources in your environment that are reachable from the public internet. Network Scanning probes your resources from the internet to detect actual reachability, complementing the existing network reachability findings in Security Hub that identify configurations that could make a resource reachable. It discovers public IP addresses, virtual machines, and load balancers across your AWS and Azure environments, identifies reachable ports, and determines what services are running behind them. Each reachable port generates a Security Hub finding with evidence of the port and service discovered. Security Hub Exposures then automatically correlates these findings with other findings and resource configurations to determine broader risk. Existing customers can enable Network Scanning in individual accounts and Regions, or across an organization through a configuration policy. For new customers, Network Scanning is on by default. It is included with Security Hub Essentials at no additional cost.
  • Security Hub also extends unified security management to Microsoft Azure – Security Hub now monitors Microsoft Azure resources, providing unified posture management, vulnerability management, and security response across both clouds. It automatically discovers Azure VMs, container images, Function Apps, and identities, and evaluates them for misconfigurations, internet exposure, and software vulnerabilities. AWS and Azure findings appear in the same prioritized view with the same formats and automation workflows.
  • Amazon SageMaker Studio integrates with Hugging Face for one-click model deployment and customization – You can now go from discovering a model on Hugging Face to working with it in SageMaker Studio in a single click. Select any supported model on Hugging Face and choose “Customize on SageMaker AI” or “Deploy on SageMaker AI” to land directly on the corresponding workflow page with the model pre-loaded. New customers receive a Studio environment created in seconds with pre-configured permissions for serverless model customization (including fine-tuning with custom reward functions for reinforcement learning), model evaluation, and deployment to SageMaker or Bedrock endpoints. Verified customers receive default GPU access to G5, G6, and G4dn instances without requesting quota increases, and quota utilization is visible directly inside the Studio environment.
  • Amazon EKS Auto Mode and Amazon ECS Managed Instances reduce GPU management fees by up to 60% – Beginning July 1, 2026, EKS Auto Mode and ECS Managed Instances reduce management fees for accelerated instance types: G-series fees are down 35%, and P-series and AWS Trainium fees are down 60%. The reductions apply automatically to existing clusters and require no action from customers. Both services include capabilities built for accelerated workloads. EKS Auto Mode provides automatic parallel image pulling on GPU instances with local NVMe storage and accelerator-aware node repair. ECS Managed Instances provides GPU metrics through Amazon CloudWatch Container Insights and automatic health monitoring for GPU hardware failures.
  • Amazon Aurora DSQL change data capture (CDC) is now generally available – Aurora DSQL CDC streams the results of insert, update, and delete operations as change events to Amazon Kinesis Data Streams. You can use it to synchronize data across microservices, trigger Lambda functions, or deliver changes to S3, Redshift, and OpenSearch Service through Amazon Data Firehose. CDC streaming is designed to have zero impact on database workload performance and requires no infrastructure to manage.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts you may find useful:

  • Building secure AI agents at scale: Introducing Loom for AWS – Loom is an open-source enterprise platform for building agents with AWS Strands Agents and deploying them on Amazon Bedrock AgentCore Runtime. It provides a unified management UI and backend API with identity provider integration, scope-based authorization, multi-persona navigation, and full lifecycle management for agents, memory, MCP servers, and agent-to-agent integrations. Loom enforces automated resource tagging for cost attribution, implements RBAC and ABAC for multi-tenant security, uses paved-path blueprints for agent deployments, manages identity propagation through delegated actor chains, integrates with AWS Agent Registry for discovery and governance, and supports human-in-the-loop review before sensitive actions. The project is available in AWS Labs on GitHub.
  • Introducing Claude apps gateway for AWS – The Claude apps gateway is a self-hosted control plane that gives organizations centralized control over access, cost, and policy for Claude Code and Claude Desktop. It connects to any OIDC-compliant identity provider, enforces managed settings on every request, routes inference to Amazon Bedrock or Claude Platform on AWS, and supports per-user and per-group spend caps. The gateway runs as a stateless container in your private network, backed by a PostgreSQL database for short-lived sign-in state. No long-lived secrets are stored on developer machines. Deploy it through Amazon Bedrock to keep data within the AWS security boundary, or through Claude Platform on AWS for the native Claude platform experience.
  • Introducing OAuth support for AWS MCP Server – You can now connect agents to the AWS MCP Server using browser-based OAuth with the same credentials you use for the AWS Console or CLI. The new sign-in path supports IAM federation, AWS IAM Identity Center, and root or IAM users. AWS Sign-In issues short-lived access tokens and refresh tokens, with automatic token management so developers stay authenticated across restarts. For headless use cases, a non-interactive flow lets applications with existing AWS credentials obtain OAuth access tokens through the create-oauth2-token-with-iam API. New governance controls include OAuth-specific IAM condition keys, token introspection and revocation, dynamic client registration, and CloudTrail audit elements.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building.

Wishing everyone a restful and enjoyable summer. Whether you’re building, learning, or recharging, I hope you find time for all three. I’ll be heading to Scandinavia for a few weeks to trade the heat for some cooler weather and longer evenings. Come back next week for more news!

— Esra

Prevent data exfiltration: AWS egress controls for cloud workloads

Post Syndicated from Meriem SMACHE original https://aws.amazon.com/blogs/security/prevent-data-exfiltration-aws-egress-controls-for-cloud-workloads/

When securing an Amazon Web Services (AWS) environment, teams naturally prioritize inbound controls, firewalls, WAFs, and access policies, because that’s where the most visible threats originate. Outbound traffic, on the other hand, tends to get less attention. It’s often left open by default to avoid breaking application dependencies and because the risk feels less immediate. But overlooking egress means missing a key layer of defense. Without visibility into what’s leaving your network, it’s harder to detect unintended data flows, whether from misconfigured services, overly broad permissions, or workloads with unauthorized access.

Real-world incidents highlight why egress controls deserve attention across both traditional cloud workloads and emerging AI-driven architectures.

In traditional cloud environments, application-level security issues remain a persistent threat. For example, when CVE-2025-55182 (React2Shell) was publicly disclosed in December 2025, multiple organized groups began exploitation attempts within hours, targeting unpatched React Server Components to achieve remote code execution. After a workload is accessed by an unauthorized party, they typically establish outbound command-and-control channels and begin exfiltrating data. Without egress controls in place, that outbound traffic can flow freely, and the unauthorized access might go unnoticed until a compliance audit, customer complaint, or incident notification forces discovery.

Agentic AI systems introduce a new dimension to this risk. The OWASP Top 10 for Agentic Applications identifies threats such as Agent Goal Hijack (ASI01), where unauthorized parties manipulate an autonomous agent’s objectives to silently exfiltrate data, and Unexpected Code Execution (ASI05), where an agent with unauthorized access generates and runs potentially damaging code that establishes reverse shells or transfers sensitive data to external endpoints. As organizations deploy AI agents with access to tools, APIs, and code interpreters, these agents become high-value targets, and their outbound network activity must be constrained with the same rigor as any other workload.

In both scenarios, the common thread is unauthorized outbound traffic. In this post, we show you how to implement layered egress detection and protection using AWS services working together to reduce unauthorized data transfer risk, whether the source is an application with unauthorized access or a manipulated AI agent.

Architecture overview

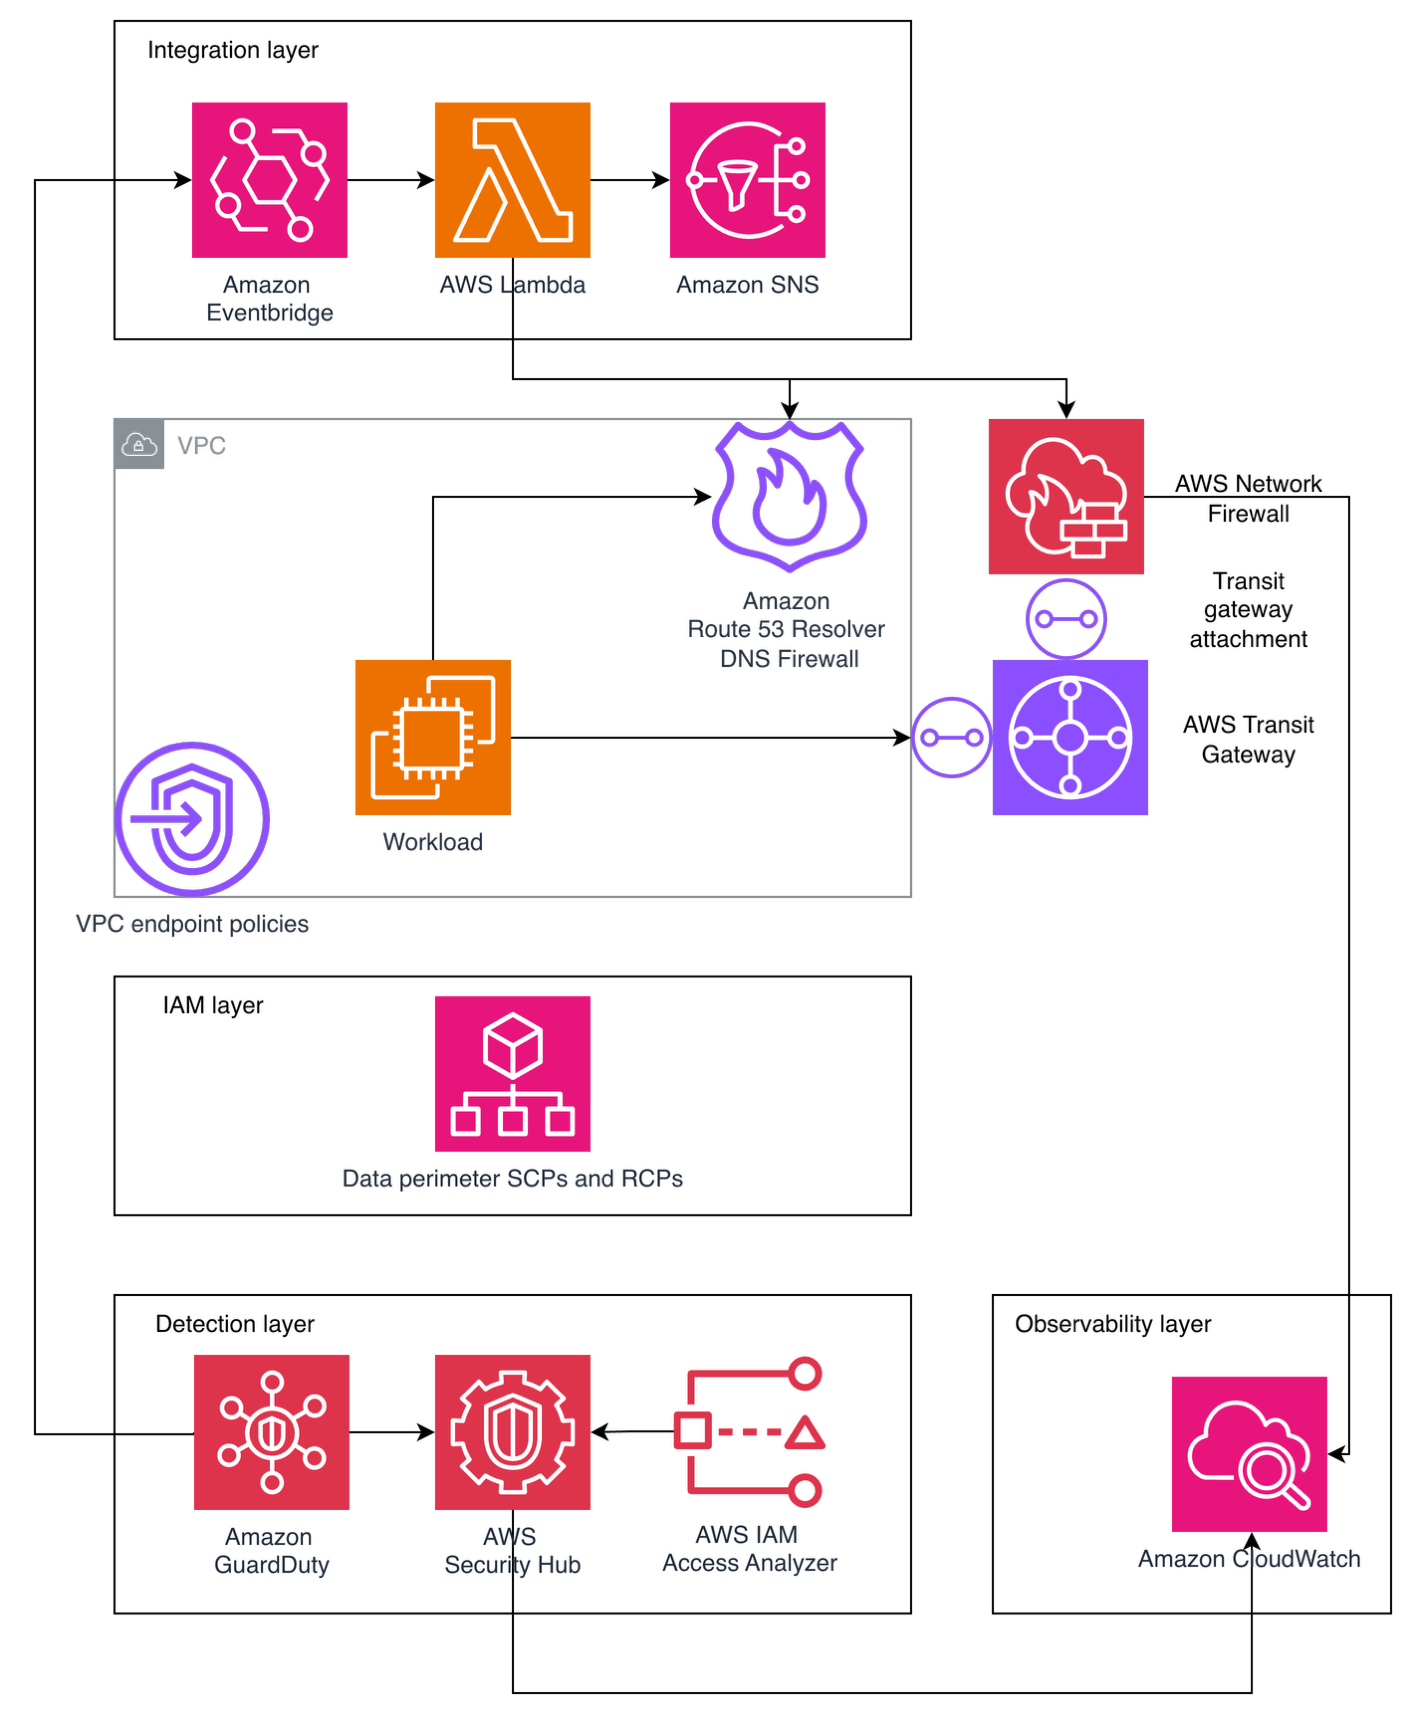
Figure 1: Hub-and-spoke egress control architecture

Figure 1: Hub-and-spoke egress control architecture

The following architecture, shown in Figure 1, illustrates one approach to implementing a hub-and-spoke network pattern for a multi-account AWS environment. Note that alternative designs might be appropriate depending on your organizational requirements and constraints.

Application workloads reside in spoke virtual private clouds (VPCs) that connect to an AWS Transit Gateway, which serves as the central hub for routing inter-VPC and internet-bound traffic while enforcing network segmentation through carefully crafted route tables. Spoke VPCs use VPC endpoints for secure AWS service access, keeping traffic within the AWS network where possible. VPC endpoint policies are applied as key data perimeter controls, restricting which principals can access AWS services and which resources can be accessed through these endpoints.

Internet-bound traffic is routed through a transit gateway-attached AWS Network Firewall, which inspects and filters outbound flows before they reach the internet. This centralized routing model scales horizontally by adding spoke VPCs without modifying the inspection infrastructure, making it well suited for organizations that have multiple AWS accounts.

It’s important to understand that Amazon Route 53 Resolver DNS Firewall must be deployed across your VPCs to filter DNS queries that resolve through the Route 53 VPC Resolver. (DNS queries sent directly to other DNS resolvers bypass it, but can be filtered with AWS Network Firewall.) The DNS firewall uses both managed and custom domain lists to filter DNS queries, blocking resolution of known unauthorized domains before any network connection is established.

Data perimeter controls are enforced at multiple layers: service control policies (SCPs) and resource control policies (RCPs) at the AWS Organizations level, VPC endpoint policies at the network level, and resource policies on individual services. AWS IAM Access Analyzer is deployed at the organization level to continuously detect publicly accessible or externally shared resources.

A detection layer comprising Amazon GuardDuty, AWS Security Hub, and IAM Access Analyzer provides continuous monitoring and threat detection. Findings are routed through an integration layer using Amazon EventBridge, which triggers AWS Lambda-based automated remediation and sends notifications using Amazon Simple Notification Service (Amazon SNS). This integration layer also feeds back into your network controls, automatically updating Network Firewall deny rules and DNS Firewall block lists based on detected threats.

Centralized observability is achieved through Amazon CloudWatch Logs and CloudWatch dashboards. Network Firewall flow logs and alert logs are collected centrally to support incident investigation and compliance reporting.

This architecture applies equally to traditional application workloads and AI-driven workloads. An AI agent running on Amazon Bedrock, for example, typically sits inside a spoke VPC. When that agent invokes an external API or attempts to reach the internet, its traffic follows the same path through Transit Gateway and Network Firewall as any Amazon Elastic Compute Cloud (Amazon EC2) or container workload. The agent doesn’t get a special lane out, it’s subject to the same domain allow-lists, the same DNS filtering, and the same data perimeter policies.

That said, agents often need outbound access to invoke external tools or third-party APIs as part of their normal operation, which makes allow-list design more nuanced. You will want to scope allowing domains tightly to the specific endpoints your agents legitimately need, rather than opening broad categories. Complementing these network-layer controls with application-layer guardrails such as Amazon Bedrock Guardrails—which can filter harmful content and detect prompt attacks before they reach the network layer—adds another layer of defense.

Preventive controls

The following preventive controls block data exfiltration before it occurs. Because they actively disrupt traffic, reserve them for activity that is confirmed or highly likely to be potentially damaging.

AWS Network Firewall

Consider this scenario: an unauthorized party compromises an EC2 instance in one of your spoke VPCs and attempts to exfiltrate sensitive data to an external server. Now consider an agentic AI scenario: an unauthorized party uses prompt injection to hijack an AI agent’s goal (OWASP ASI01), redirecting it to exfiltrate training data to an external endpoint. Network Firewall is designed to block this attempt because the unauthorized destination isn’t on the approved domain allow-list—the same control that stops an EC2 instance with unauthorized access— also stops a manipulated AI agent.

Without centralized egress inspection, that traffic flows directly to the internet through a NAT gateway. Network Firewall prevents this by providing centralized, Layers 3–7 deep packet inspection with advanced threat intelligence capabilities, including IP address, port, and protocol filtering; plus packet content inspection using Suricata-compatible rules.

In this architecture, Transit Gateway funnels internet-bound traffic from multiple spoke VPCs through Network Firewall for centralized inspection. The firewall endpoint becomes the target for 0.0.0.0/0 routes, routing outbound internet traffic for inspection before reaching NAT gateways for address translation. In both scenarios, Network Firewall blocks the exfiltration attempt at the network layer before data leaves your environment. Its key capabilities include:

  • Domain name filtering: Block traffic to unauthorized destinations (such as a command-and-control server at *.untrusted-domain.com)
  • IP and port rules: Define explicit allow-lists for external IPs your applications truly need, blocking everything else
  • Domain category filtering: Block entire categories of domains that your workloads should never communicate with
  • IDS and IPS: Detect and block known attack patterns in outbound traffic using Suricata-compatible rules
  • Port and protocol enforcement: Help ensure only expected protocols use their designated ports (for example, only HTTPS on TCP port 443), preventing protocol tunneling
  • Geographic IP filtering: Block outbound traffic to geographic regions where your organization has no business relationships
  • TLS decryption: Inspect encrypted traffic to detect exfiltration attempts hidden within HTTPS connections
  • Threat intelligence integration: Use managed threat intelligence (such as active threat defense that uses the Amazon threat intelligence system MadPot) feeds or custom Suricata rules to detect unexpected patterns
  • Automatic scaling: Handles up to 100 Gbps per Availability Zone

For multi-account environments, AWS Firewall Manager can centrally deploy and manage Network Firewall across your organization’s accounts, helping maintain consistent egress rules everywhere. Additionally, AWS Network Firewall Proxy (in preview) offers explicit proxy capabilities with granular HTTP/HTTPS filtering—including URL path and HTTP method-level controls—for workloads that require application-layer inspection of outbound web traffic.

Route 53 Resolver DNS Firewall

DNS queries made through Route 53 VPC Resolver don’t pass through the outbound network path inspected by Network Firewall or third-party firewalls. Unauthorized parties can take advantage of this by encoding sensitive data within DNS queries to external servers, a technique known as DNS tunneling. This risk extends to agentic AI workloads. An agent with code execution capabilities (OWASP ASI05) could be tricked into running a script that encodes sensitive data (like customer records, model weights, API keys) into DNS queries directed at an externally controlled nameserver. DNS Firewall is designed to block these queries regardless of whether they originate from a traditional workload or an AI agent, because the filtering happens at the resolver level before any connection is established.

Because DNS traffic is essential for normal operations and often overlooked in security architectures, it represents a common unauthorized data exfiltration channel. Route 53 Resolver DNS Firewall closes this gap by filtering and potentially blocking outbound DNS queries from your VPCs. Its core capabilities consist of:

  • Block unauthorized domains: AWS provides managed domain lists, including an Aggregate Threat List covering malware, ransomware, botnet, spyware, and DNS tunneling
  • Enforce allow-lists: Permit only queries to approved domains, blocking everything else
  • DNS Firewall Advanced features: AI and machine learning (AI/ML)-backed detection of DNS tunneling, Domain Generation Algorithms (DGAs), and dictionary DGAs

Configuration is straightforward: Create rule groups with domain match lists and actions (block, allow, and alert), then associate them with your VPCs. The DNS resolver applies these rules to every DNS query made from instances in the VPC through Route 53 Resolver. This prevents unauthorized parties from using DNS tunneling to exfiltrate data, a technique that completely bypasses inspection by firewalls in the egress VPC.

For a deeper look at the risks associated with DNS exfiltration and DNS Firewall Advanced capabilities, see Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall.

Data perimeters

A data perimeter is a set of preventive guardrails that allow only your trusted identities to access trusted resources from expected networks. While the preceding controls secure the network paths out of your environment, data perimeters secure the API-level paths, helping to ensure that even if an unauthorized party gains access to valid credentials, they can’t use AWS service APIs to move data to resources outside your organization.

This comprehensive approach uses three primary AWS capabilities working together:

  1. Service control policies (SCPs): Organization-wide preventive controls that restrict what identities can do. In the context of egress protection, SCPs can prevent users from creating resources that bypass your egress controls (for example, preventing the creation of VPCs without DNS Firewall associations or blocking the use of services that could establish alternative outbound paths).
  2. Resource control policies (RCPs): Controls that restrict API access to your resources. While RCPs aren’t directly egress controls, they act as a complementary layer. For example, they can block attempts to access your Amazon Simple Storage Service (Amazon S3) buckets from outside your organization at the resource level.
  3. VPC endpoint policies: VPC endpoints enable private communication with AWS services without traffic going through the internet. VPC endpoint policies are resource-based AWS Identity and Access Management (IAM) policies that govern what can be accessed through that endpoint. This is where data perimeters most directly function as an egress control.

Consider the following VPC endpoint policy that restricts Amazon S3 access through the endpoint to only S3 buckets within your organization, directly preventing an insider or a workload with unauthorized access from copying data to an external S3 bucket:

{
  "Statement": [{
    "Sid": "DenyAccessToNonOrgBuckets",
    "Effect": "Deny",
    "Principal": "*",
    "Action": "s3:*",
    "Resource": "*",
    "Condition": {
      "StringNotEqualsIfExists": {
        "aws:ResourceOrgID": "<my-org-id>"
      }
    }
  }]
}

This policy is designed to deny any Amazon S3 operation through this VPC endpoint unless the target S3 bucket belongs to your organization. Without this control, a workload with unauthorized access could use aws s3 cp to copy sensitive data to an externally controlled bucket in a different AWS account.

Data perimeter policies don’t grant new permissions, they narrow what’s accessible by establishing guardrails, acting as a second authorization layer. By implementing these perimeters using IAM condition keys like aws:PrincipalOrgID, aws:ResourceOrgID, aws:SourceVpc, and aws:SourceVpce, you create layered permissions guardrails that help prevent unintended access patterns and configuration errors.

For more information on implementing perimeter controls, explore the Building a Data Perimeter AWS whitepaper.

Detective controls

The following detective controls surface data exfiltration attempts after they occur. Because they observe rather than disrupt traffic, you can apply them broadly to flag unexpected activity for investigation. Use the findings to identify recurring unauthorized patterns that can graduate into preventive controls.

Amazon GuardDuty: Detective control for egress threats

GuardDuty serves as your critical detection layer for egress protection, continuously monitoring for outbound threats that evade or take advantage of your preventive controls. GuardDuty identifies behavioral anomalies and attack patterns that indicate active data exfiltration attempts. Its egress-focused detection capabilities include:

  • DNS-based data exfiltration detection: The Trojan:EC2/DNSDataExfiltration finding alerts when EC2 instances are transferring data through DNS channels. GuardDuty also identifies queries to DGA domains commonly used for command-and-control communication.
  • Known malicious actor detection: Exfiltration:S3/MaliciousIPCaller triggers when Amazon S3 data APIs like GetObject or CopyObject are invoked from IP addresses on AWS threat intelligence feeds, signaling active data extraction attempts.
  • Multi-step attack sequence correlation: GuardDuty Extended Threat Detection correlates multiple unexpected events to identify multi-stage exfiltration campaigns. For example, AttackSequence: S3/CompromisedData detects when unauthorized parties modify S3 bucket policies to broaden access and then systematically extract data using stolen credentials.

GuardDuty findings serve dual purposes in your egress strategy. Alerts about attempted exfiltration that failed confirm your preventive layers (Network Firewall, DNS Firewall, and data perimeters) are functioning effectively: the threat was detected because it progressed far enough to trigger behavioral analysis, but your controls blocked the actual data loss. Conversely, findings indicating successful exfiltration trigger immediate incident response workflows, enabling you to contain active incidents, revoke stolen credentials, and quarantine affected resources before significant damage occurs.

Integrate GuardDuty with Security Hub for centralized correlation across your security services and implement automated response through EventBridge and Lambda functions to enable real-time containment when high-severity exfiltration findings occur.

IAM Access Analyzer

IAM Access Analyzer helps identify potential data exfiltration paths by detecting resources accessible from outside your AWS account or organization. It uses automated reasoning technology to analyze resource-based policies and identify which of your resources can be accessed by external entities (principals outside your zone of trust), continuously monitoring public and cross-account access.

External access analyzers identify resources shared with external principals (such as other AWS accounts or public access). For example, when an S3 bucket is configured to allow access outside your zone of trust through bucket policies, ACLs, or access points, IAM Access Analyzer generates a finding with details about the access path, including the external principal and the level of access granted. Security teams can respond by taking immediate action to remove unintended access or by setting up automated notifications through EventBridge to engage development teams for remediation.

AWS Security Hub

Security Hub exposure findings provide a comprehensive view of potential security risks by correlating data from multiple AWS security services. These findings identify when resources might be vulnerable to data exfiltration by integrating intelligence from GuardDuty (for threat detection), Amazon Inspector (for vulnerability assessment), Security Hub CSPM (for configuration compliance), and Amazon Macie (for sensitive data discovery). For example, it can identify when a publicly exposed S3 bucket contains sensitive data and isn’t encrypted at rest, flagging it as a potential data exfiltration risk that requires immediate attention.

AWS Shield network security director (in preview) complements Security Hub by discovering and analyzing your network topology to identify resources with unrestricted outbound internet access, helping you detect potential egress blind spots across your environment.

Egress security strategy

You don’t need to implement all these controls at once. The following phased approach lets you build your egress security posture incrementally, at a pace that matches your organization’s operational maturity and risk tolerance.

  • Phase 1 – Quick wins: Enable Route 53 DNS Firewall across your VPCs to close the DNS exfiltration gap. Enable GuardDuty across your accounts for baseline threat detection.
  • Phase 2 – Foundational: Deploy organization-wide data perimeters (SCPs, RCPs, and VPC endpoint policies). Deploy Network Firewall as a transit gateway-attached firewall.
  • Phase 3 – Efficient: Enable IAM Access Analyzer for continuous external access detection. Implement automated remediation through EventBridge and Lambda to update firewall rules in real time. Centralize findings in Security Hub with automated alerting.

Conclusion

Egress security isn’t a single control—it’s a layered strategy. Start by assessing your current posture across network filtering, DNS security, data perimeters, and detective controls. Identify the gaps, then follow the phased approach outlined in this post to close them incrementally. Regular testing through simulated exfiltration attempts validates that your controls work effectively. These controls apply with equal force to agentic AI workloads, where manipulated agents can become unintended exfiltration vectors. Put egress under control and turn your outbound blind spots into monitored checkpoints.

If you have feedback about this post, submit comments in the Comments section below.


Merriem-SMACHE

Meriem SMACHE

Meriem is a Security Specialist Solutions Architect at AWS, supporting customers in the design and deployment of resilient cloud and AI solutions, from generative AI workloads to fully autonomous agentic systems, that meet their regulatory requirements and security needs.

Maxim Raya

Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.

Threat tactic spotlight: Subdomain takeover

Post Syndicated from Matt Gurr original https://aws.amazon.com/blogs/security/threat-tactic-spotlight-subdomain-takeover/

In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.

Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.

AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.

Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.

Quick DNS Primer

CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.

Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.

What is subdomain takeover?

A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.

A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:

Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.

Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.

AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.

Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.

MITRE ATT&CK classifies this technique under T1584.001: Compromise Infrastructure – Domains.

Analyzing an example scenario

Consider the following scenario:

You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.

Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.

Figure 1: S3 bucket configured as a static website

Figure 1: S3 bucket configured as a static website

As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.

Figure 3: Resource deleted without removing the CNAME record

Figure 3: Resource deleted without removing the CNAME record

With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.

Figure 4: Subdomain takeover happens

Figure 4: Subdomain takeover happens

Potential impacts of a sub-domain takeover

Consider these potential impacts:

Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.

Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.

Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.

Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.

Proactive detection

AWS Config for proactive detection

For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.

Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.

Why use AWS Config inventory instead of DNS resolution checks?

A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.

By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.

Implementation approach:

Account-level vs. organization-level scope

The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.

For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.

We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.

The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.

The Config rule should focus on known AWS resource patterns:

  • S3: *.s3.amazonaws.com, *.s3-website-<region>.amazonaws.com
  • CloudFront: *.cloudfront.net
  • Elastic Beanstalk: *.elasticbeanstalk.com

Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.

NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.

Figure 5: Dangling DNS Detection Solution

Figure 5: Dangling DNS Detection Solution

Reference implementation:

We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.

Deployment:

# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM

The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.

Mitigating the effects

Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.

Prevention: Standard operating procedure

The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:

  1. Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
  2. Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
  3. Deprovision the resource that you no longer want to use.
  4. Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.

Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.

Prevention: S3 account regional namespaces

As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:

Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.

Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.

Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.

For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.

Response: Notification and remediation

When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.

The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.

Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.

Conclusion

Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:

Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.

Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.

Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.

Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.

The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.

If you have feedback about this post, submit comments in the Comments section below.


Matt Gurr

Matthew Gurr

Matthew is the Senior Incident Response lead in the Asia-Pacific region for the AWS Customer Incident Response Team (AWS CIRT). He has a passion for helping customers proactively prepare for a security event. In his spare time, he enjoys cycling, music, and reading.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS leading the Infrastructure Security and Compliance Technical Field Communities. He drives security architecture for enterprise customers across financial services, healthcare, and retail, specializing in cloud security transformation and regulatory compliance frameworks. Before AWS, Luis architected security solutions in hybrid cloud environments.

Geoff Sweet

Geoff Sweet

Geoff has been in industry since the late 1990s. He began his career in electrical engineering. Starting in IT during the dot-com boom, he has held a variety of diverse roles, such as systems architect, network architect, and, for the past several years, security architect. Geoff specializes in infrastructure security.

Ariam Michael

Ariam Michael

Ariam is a Solutions Architect at AWS. She has supported various customers in the Worldwide Public Sector, specifically SLG and Federal Civilian customers. She is passionate about security, specifically Data Protection helping customers implement encryption and best practices.

Operationalizing AWS security: A maturity roadmap

Post Syndicated from Joseph Sadler original https://aws.amazon.com/blogs/security/operationalizing-aws-security-a-maturity-roadmap/

Enabling security tooling is the starting point. Making it operational—where findings drive decisions, response times are measurable, and your security posture improves week over week—is where most organizations struggle.

This blog post provides a phased maturity roadmap for organizations that have already enabled AWS Security Hub and Amazon GuardDuty. These two services form the foundation of a cloud-centered security operations capability on AWS. Security Hub provides centralized security posture management and aggregates findings from multiple AWS security services, while GuardDuty provides intelligent threat detection by continuously monitoring for malicious activity and unauthorized behavior. For any production or enterprise AWS environment, having both services enabled across all accounts and AWS Regions is a baseline expectation; not because they’re optional add-ons, but because effective security operations require both the ability to detect threats and the ability to understand your overall security posture. If you haven’t yet enabled them, the Security Hub documentation and GuardDuty documentation provide setup guidance, including multi-account deployment with AWS Organizations.

Customers consistently tell us that while individual AWS security service documentation is thorough, what’s missing is a consolidated operational playbook—one resource that ties the services together into a working security operations practice with clear phases, progression criteria, and an operational cadence. That’s the gap this post fills. Rather than covering how each feature works (the documentation does that well), this post focuses on when and why to use each capability, and how to build the organizational habits that make them effective.

What follows is a six-phase roadmap for moving from these services are active to these services are driving our security operations. Each phase builds on the previous one, and each is designed to deliver tangible, measurable improvement.

Phase 0: Assess your current state

Goal: Understand what’s working before changing anything.

Estimated timeline: 1–2 weeks

Move to Phase 1 when: You have a documented current-state assessment covering all the following items.

Before introducing new processes or automation, establish a clear picture of the current environment. This assessment informs every decision that follows.

Actions:

  • Findings inventory: Review existing active GuardDuty findings to determine how many there are, the severity distribution, and how old the oldest findings are. A large backlog of untouched HIGH or CRITICAL findings that have been sitting for weeks is a strong signal about where to focus first.
  • Security Hub score baseline: Determine your current compliance score against AWS Foundational Security Best Practices (FSBP) and The CIS AWS Foundations Benchmark. Check to see which standards are enabled; if multiple standards are enabled, review for overlapping standards (creating noise) or unused standards.
  • Multi-account and multi-Region check: Look to see if GuardDuty is enabled in every account and every Region, or only in Regions with active workloads. Threat actors frequently operate in Regions that organizations don’t actively monitor. Also check to see if Security Hub aggregation is configured with a delegated administrator account or if each account is being managed independently.
  • Integration check: Determine if GuardDuty findings are flowing into Security Hub and if Amazon Inspector and Amazon Macie are enabled and feeding findings in. Without integration, Security Hub might be only surfacing its own compliance checks.
  • Notification check: See if there’s an Amazon EventBridge rule configured for notifications and if so, how findings are being routed and to whom. Know if notifications are being sent using an Amazon Simple Notification Service (Amazon SNS) topic or a chat channel integration. Without a clear notification and response workflow, findings can accumulate silently in the console with no one looking at them.

Deliverable: A one-page current state assessment that identifies what’s enabled, what’s flowing where, who’s looking at it, and what’s in the existing backlog.

Phase 1: Reduce the noise

Goal: Make the signal meaningful before asking anyone to act on it.

Estimated timeline: 2–3 weeks

Move to Phase 2 when: Remaining findings represent items requiring real decisions, compliance scores reflect actual posture, and you can articulate why every suppression rule and disabled control exists.

This is the single most important phase. If this step is skipped in favor of jumping straight to automation, the result is automated chaos. Alert fatigue is the primary reason security tooling is ignored, and addressing it first is what makes everything that follows sustainable.

GuardDuty tuning:

  • Create suppression rules for known-benign findings. The goal is to suppress activity you’ve already evaluated and accepted—such as expected traffic from corporate egress IPs (based on trusted IP lists), internal tools that trigger DNS-based findings, or internet-facing resources that naturally receive port scanning. The principle: if you’ve investigated a finding and it’s expected, suppress it so your team can focus on what matters.
  • Triage every active HIGH and CRITICAL finding into three categories: needs immediate investigation (real threat, not yet reviewed), true positive, already addressed (archive using workflow status), or false positive or expected behavior (create a suppression rule). Every finding must be categorized into one of these three states.
  • Review GuardDuty protection plans and enable any that are relevant but not yet active. Organizations that enabled GuardDuty years ago might not have activated protection plans released since then (such as Runtime Monitoring, Malware Protection, RDS Protection, and Lambda Protection). Evaluate each against your workload profile and enable what applies.

Security Hub tuning:

  • Disable controls that aren’t relevant to the environment. This is the highest-value quick win. If a service isn’t in use, disable its controls. If a control is addressed by an alternative solution, disable it. A 47% compliance score where half the failures are irrelevant trains teams to ignore the dashboard entirely. See the Security Hub controls reference for the full list.
  • Choose a primary standard. AWS Foundational Security Best Practices is a strong default. The CIS AWS Foundations Benchmark adds value when there’s a specific compliance mandate. Avoid enabling PCI DSS or NIST 800-53 standards unless there’s a reporting requirement—they add significant volume without proportional signal for most organizations.
  • Configure cross-Region aggregation to the delegated administrator account if not already in place. A single aggregated view eliminates the need to check findings across multiple Regional consoles.
  • Use the workflow status field operationally. Findings should progress from NEW to NOTIFIED to RESOLVED or SUPPRESSED. If everything remains in NEW indefinitely, the system carries no operational meaning.

Deliverable: A tuned environment where remaining findings represent items that require real decisions. Compliance scores should now reflect your organization’s actual security posture rather than noise.

Phase 2: Build the notification and routing layer

Goal: Get the right findings to the right people at the right time.

Estimated timeline: 2–3 weeks

Move to Phase 3 when: CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked tickets, and notifications include enriched context. No action is taken until a person or an automation is informed that something needs attention.

Architecture: Security Hub to EventBridge rule to routing logic to destination

Tiered notification strategy:

CRITICAL Page on-call immediately PagerDuty or Opsgenie 15 minutes
HIGH Alert security team channel Slack or Teams channel and ticket creation 4 hours
MEDIUM Create ticket for review Jira or ServiceNow 48 hours
LOW or INFORMATIONAL Batch digest Weekly email summary or dashboard review Next review cycle

Key design decisions:

  • Route from Security Hub, not individual services. Because findings from GuardDuty, Inspector, Macie, and Security Hub compliance checks all aggregate in Security Hub, build your EventBridge rules there for centralized management.
  • Create a fast path for the most dangerous finding types. Certain GuardDuty findings, particularly those involving credential exfiltration, cryptocurrency activity, trojans, and active compromises, warrant a separate, faster routing path that bypasses normal triage. Identify these based on your threat model and the GuardDuty finding types reference.
  • Enrich notifications before delivery. A raw JSON finding in a chat channel provides little actionable context. Use an AWS Lambda function to format notifications with the information responders need: account alias, Region, Amazon Resource Name (ARN), finding type, severity, a console deep link, and a plain-language description. The Security Hub CloudWatch Events integration guide describes the event format.

Deliverable: A working notification pipeline where CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked work items, and LOW and INFORMATIONAL findings are batched for periodic review.

Phase 3: Build automated remediation for high-confidence findings

Goal: For findings where the correct response is deterministic, remove the human from the loop.

Estimated timeline: 3–4 weeks

Move to Phase 4 when: At least 3–5 high-confidence finding types have automated responses deployed with audit trails, and the team has established a process for evaluating new auto-remediation candidates.

The guiding principle: Only auto-remediate when all three conditions are met: the finding is high-confidence, the response is deterministic, and the blast radius of the automated action is limited. Automated remediation must not create the risk of a production outage.

Decision framework:

Confidence level High – no false positive risk Medium – context-dependent Low – requires investigation
Response complexity Single, well-defined action Multiple steps or judgment calls Requires forensic analysis
Blast radius Limited to one resource Could affect dependent services Production-wide impact
Rollback difficulty Straightforward to reverse Moderate effort to reverse Difficult or impossible to reverse

Common auto-remediation categories:

  • Instance isolation for confirmed compromise findings (cryptocurrency mining, malware, and trojans): Replace the security group, snapshot volumes for forensics, and notify.
  • Credential revocation for confirmed credential compromise: Attach deny-all policies, revoke sessions, and deactivate access keys as appropriate to the credential type.
  • Compliance drift correction for deterministic misconfigurations: Re-enable Amazon Simple Storage Service (Amazon S3) Block Public Access, revoke overly permissive security group rules, and re-enable AWS CloudTrail logging.
  • Notification-only escalation for findings that require human judgment before action: Amazon Elastic Block Store (Amazon EBS) encryption gaps (require migration) and access key rotation (requires coordination with the key owner).

For implementation, AWS provides Security Hub Automated Response and Remediation (SHARR), a solution that includes pre-built remediation playbooks deployed as AWS Step Functions workflows triggered by EventBridge. This is a strong starting point—evaluate the provided playbooks, enable the ones that fit, and extend with custom remediations as needed.

Note: For findings that recur because the environment lacks preventive guardrails, the best long-term response is often a service control policy (SCP) that prevents the misconfiguration from occurring in the first place. Phase 5 covers this preventive controls layer.

Deliverable: A library of automated and semi-automated remediation runbooks with full audit trails, and a documented decision framework the team uses to evaluate new auto-remediation candidates.

Phase 4: Build the operational rhythm

Goal: Turn security findings management into a sustained organizational practice, not a one-time cleanup.

Estimated timeline: 4–6 weeks to establish, then ongoing

Move to Phase 5 when: The weekly cadence has been running consistently for at least 8 weeks, monthly metrics show positive trends, and the first quarterly review has been completed.

This is where many organizations stall, and it’s the most important phase in the entire roadmap. The technology is working, the notifications are flowing, automated remediations are firing, but there’s no organizational habit built around it. Without this phase, everything you’ve built in Phases 0–3 will gradually decay. Suppression rules will go stale, new team members won’t know the system exists, and findings will start accumulating again. The operational rhythm is what converts a security tooling deployment into a security operations practice.

Weekly security review (30 minutes)

Attendees: Security team lead, cloud platform team representative, rotating engineering lead from an application team

Why the rotating engineering lead matters: Security findings don’t exist in a vacuum; they’re generated by workloads that engineering teams own. Rotating an engineering representative through this meeting accomplishes three things: it builds security awareness across the organization, ensures findings are routed to people with the context to resolve them, and creates organizational accountability beyond the security team.

Agenda template:

5 minutes Compliance score trend – Review Security Hub scores by account and standard. Is the trend improving, declining, or flat? If declining, why? Security lead Identified regression areas
5 minutes Critical and high findings review – Walk through new HIGH and CRITICAL GuardDuty findings from the past week. Are there any that need immediate escalation? Security lead Escalation actions assigned
10 minutes Top five failing controls – Identify the five Security Hub controls with the most failures. Assign an owner and a target date for each. Platform lead Owners and dates documented
5 minutes Automation review – Did any auto-remediations fire this week? Did they work correctly? Were there any false triggers? Security lead Automation adjustments queued
5 minutes Tuning decisions – Are new suppression rules needed based on this week’s findings? Are any new finding types candidates for auto-remediation? All Tuning backlog updated

Running the meeting effectively:

  • Keep a running document (such as a wiki page or shared document) that captures decisions and action items week over week. This becomes your institutional memory.
  • If the compliance score hasn’t moved in over 3 weeks, that’s a signal. Either the assigned work isn’t happening, or the remaining findings are genuinely difficult to address. Both need to be discussed.
  • Track action items from previous weeks. A review that generates action items but never follows up on them will lose credibility and attendance quickly.

Escalation procedures

Define clear escalation paths before they’re needed:

CRITICAL finding not acknowledged within the SLA Auto-escalate to security team manager 15 minutes after SLA breach
HIGH finding not resolved within the SLA Escalate to finding owner’s manager 4 hours after SLA breach
Compliance score drops more than 5 points in a week Escalate to cloud platform team lead for investigation Next business day
Auto-remediation failure Page security on-call Immediate
New finding type not covered by existing runbooks Add to weekly review agenda for triage and runbook development Next weekly review

Monthly metrics report

Compile these metrics monthly and review them with security and engineering leadership. The goal is to tell a story about whether the organization’s security posture is improving, stable, or degrading, and why.

Mean time to acknowledge (MTTA) for CRITICAL findings Are findings being seen promptly? Decreasing month over month
Mean time to resolve (MTTR) for CRITICAL and HIGH findings Are findings being acted on? Decreasing month over month
Security Hub compliance score by standard, by account What is the posture trend over time? Increasing month over month
Number of active GuardDuty findings by severity Is the backlog growing or shrinking? Decreasing for HIGH and CRITICAL
Findings auto-remediated compared to manually resolved Is automation delivering value? Auto-remediation ratio increasing
Number of suppressed findings (with quarterly justification review) Is noise being managed, or are problems being hidden? Stable or decreasing
New findings introduced compared to resolved this month Is the organization getting ahead or falling behind? More finding resolved than introduced
SLA adherence rate by severity Are response commitments being met? More than 95% for CRITICAL, and more than 90% for HIGH

Building the dashboard: Use Amazon CloudWatch dashboards for real-time operational visibility or Amazon QuickSight connected to Security Hub findings through Amazon Security Lake for historical trend analysis and executive reporting. The dashboard should be visible to—and regularly viewed by—everyone in the weekly review, not locked in a security team tool.

Quarterly reviews

The quarterly review is a deeper inspection of the system itself; not just the findings, but the machinery processing them.

Quarterly review checklist:

  • Suppression rules audit: Review every active suppression rule to determine if the underlying condition is still present and the suppression is still justified. Document the review outcome for each rule.
  • Disabled controls audit: Review every disabled Security Hub control. Check that the justification is still valid and if the environment changed (for example, a service that wasn’t in use is now in use).
  • Automation audit: Review AWS Identity and Access Management (IAM) roles used by remediation functions and verify least privilege. Review execution logs for any anomalies or failures that weren’t caught.
  • New capabilities review: Evaluate newly released GuardDuty protection plans and Security Hub controls from that quarter. AWS releases new detection and compliance capabilities regularly. If you’re not reviewing them quarterly, you’re accumulating blind spots.
  • Process effectiveness review: Determine if the weekly meeting is well-attended and if action items are being completed. Make sure SLAs are being met. If attendance, action item completion, and SLA compliance aren’t where they should be, explore structural changes to address the gaps.

Operational maturity scoring

Use this rubric to assess the maturity of your operational rhythm itself. Score each dimension 1–3 and use the total to track progress over time.

Review cadence One time reviews when someone remembers Weekly review happens, but attendance is inconsistent Weekly review is consistently attended with documented outcomes
Metrics tracking No metrics captured Metrics are collected monthly but not acted on Metrics drive decisions and declining trends trigger specific actions
Finding ownership Findings sit in queue with no owner Findings are assigned to teams but SLAs aren’t tracked Every finding has an owner, SLAs are tracked, and breaches are escalated
Automation management Set-and-forget automations Automation logs are reviewed periodically Automation is reviewed weekly, and new candidates are evaluated continuously
Tuning lifecycle Suppression rules created but never reviewed Annual review of suppressions and disabled controls Quarterly reviews with documented justification for every rule
Cross-team engagement Security team works in isolation Platform team participates Engineering teams actively participate and own remediation

Scoring (revisit quarterly):

  • Beginning: 6–9
  • Established: 10–14
  • Optimized: 15–18

Deliverable: A documented operational cadence with clear ownership (consider a RACI matrix), metrics dashboards, escalation procedures, and a continuous improvement loop. The cadence should survive team member turnover—if it depends on one person remembering to run it, it’s not yet operational.

Phase 5: Mature the architecture

Goal: Fill remaining gaps and build toward a comprehensive security operations capability. Estimated timeline: Ongoing. Prioritize based on organizational risk profile and compliance requirements.

  • Amazon Inspector integration: Enable Amazon Inspector for Amazon Elastic Compute Cloud (Amazon EC2) instances, Lambda functions, and Amazon Elastic Container Registry (Amazon ECR) container images. Findings flow into Security Hub automatically, adding vulnerability management alongside threat detection and posture management. Prioritize this if you have Amazon EC2 or container workloads without an existing vulnerability scanning solution.
  • Amazon Macie: Enable Amazon Macie for S3 buckets containing potentially sensitive data. Particularly important for organizations with compliance requirements around personally identifiable information (PII), protected health information (PHI), or Payment Card Industry (PCI) data. Configure automated sensitive data discovery and route findings to Security Hub.
  • Amazon Security Lake: Amazon Security Lake centralizes security-relevant logs in OCSF format for long-term retention, forensic investigation, and threat hunting. This is valuable when you need historical analysis beyond the Security Hub retention window, or when feeding a third-party Security Information and Event Management (SIEM) tool.
  • Preventive controls layer: Convert recurring detective findings into preventive policies. Use SCPs to prevent disabling GuardDuty, Security Hub, and CloudTrail, IAM permission boundaries on developer roles, AWS WAF on public endpoints, and AWS Network Firewall for VPC traffic inspection. The pattern is to make recurring misconfigurations impossible to introduce.
  • Detective controls expansion: Use AWS IAM Access Analyzer for external access and unused access findings, AWS CloudTrail Lake for long-term queryable audit logs, and AWS Config custom rules for organization-specific compliance checks.
  • Incident response readiness: Have incident response playbooks referencing specific GuardDuty finding types, pre-built forensics infrastructure (isolated VPC, forensic AMIs, and pre-configured IAM roles), regular tabletop exercises, and AWS CloudFormation templates to deploy isolation infrastructure on demand. See the AWS Security Incident Response Guide for a comprehensive framework.

Conclusion

In this post, I provided a six-phase roadmap for operationalizing Security Hub and GuardDuty and showed that it isn’t a single project, but a progression. Phase 0 and Phase 1 can typically be completed in 3–5 weeks and deliver immediate clarity. Phases 2 and 3 build the response infrastructure that turns findings into action over the following 5–7 weeks. Phase 4 is what makes everything sustainable and is where you should invest the most attention. And Phase 5 expands the aperture from Security Hub and GuardDuty into a comprehensive security operations capability.

If you walked away from this post and did one thing, run the Phase 0 assessment this week. That single deliverable tells you exactly where to focus next. Use the following self-assessment checklist to identify your current phase, then focus on the next one. A tuned environment with working notifications and a weekly review cadence is dramatically more effective than a fully featured but neglected deployment. Start where you are, reduce the noise, build the habits, and iterate. To learn more, explore the AWS Security Hub User Guide, the Amazon GuardDuty User Guide, and the AWS Security Incident Response Guide. If you’ve implemented a similar operational cadence, or have questions about any phase, share your experience in the comments.

Self-assessment checklist

Phase 0 We know how many active GuardDuty findings exist across all accounts
We know our current Security Hub compliance score
We know whether GuardDuty is enabled in every account and region
We know who (if anyone) is reviewing findings today
Phase 1 GuardDuty suppression rules exist for known-benign activity
Irrelevant Security Hub controls have been disabled with documented justification
All active HIGH and CRITICAL findings have been triaged
Security Hub compliance scores reflect actual posture, not noise
Phase 2 HIGH and CRITICAL findings generate real-time notifications to the security team
MEDIUM findings automatically create tracked work items
Notifications include enriched context (account alias, resource ARN, and console link)
Phase 3 At least three high-confidence finding types trigger automated remediation
Auto-remediation actions have full audit trails
Remediation runbooks are documented and version-controlled
Phase 4 A weekly security review meeting occurs with defined attendees and agenda
MTTA and MTTR are tracked monthly for CRITICAL and HIGH findings
Suppression rules and disabled controls are reviewed quarterly
Security metrics trend positively over the past 3 months
Phase 5 Amazon Inspector, Macie, or Security Lake are integrated
Preventive controls (SCPs, permission boundaries) address recurring findings
Incident response playbooks exist and are tested through tabletop exercises

If you have feedback about this post, submit comments in the Comments section below.


Joseph Sadler

Joseph Sadler

Joseph is a Senior Solutions Architect on the Worldwide Public Sector team at AWS, specializing in cybersecurity and machine learning. With public and private sector experience, he has expertise in cloud security, artificial intelligence, threat detection, and incident response. His diverse background helps him architect robust, secure solutions that use cutting-edge technologies to safeguard mission-critical systems

AWS Weekly Roundup: AWS Local Zones in Istanbul, open-source ExtendDB, Kiro Web, and more (May 25, 2026)

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-local-zones-in-istanbul-open-source-extenddb-kiro-web-and-more-may-25-2026/

There’s something genuinely energizing about working with startups — something I’ve been doing intensely for more than two years now. Startups operate at a different frequency: the urgency is real, the constraints are tight, and the stakes are personal. Helping them navigate the challenge of proving their business model requires not just technical depth but a willingness to move fast, challenge assumptions, and make bets on the right architecture before the perfect data exists.
What I love most is that the work is never abstract: every decision I help a startup make has a direct impact on whether they ship on time, stay within budget, and earn the next round of confidence from their investors.

Let’s dive into this week’s AWS news.

Headlines
Now Open — AWS Local Zones in Istanbul, Türkiye — AWS has opened a new Local Zone in Istanbul, Türkiye, bringing AWS compute, storage, and networking services to one of Europe’s largest metropolitan areas. For organizations with data residency requirements in Türkiye, this Local Zone enables you to keep data within the country while still leveraging the full breadth of AWS services. The Local Zone also benefits applications that require single-digit millisecond latency — such as real-time gaming, media production, live video streaming, and financial services — by running closer to where end users actually are.

A Local Zone is a significant infrastructure investment: it requires the same level of commitment as a Region in terms of hardware, power, networking, and operational excellence. It also reflects AWS’s continued expansion into underserved markets.

For builders in Türkiye, this opens up a new set of architectural possibilities. You can now store and back up data within Turkish borders to help meet data residency requirements, and run latency-sensitive workloads in the Istanbul Local Zone while connecting seamlessly to the AWS Region — giving you the flexibility to architect hybrid applications without managing your own data center infrastructure. To learn more about our decade-long commitment, available services, customers and partners in Türkiye, visit the launch blog post.

Last week’s launches
Here are some launches and updates that caught my attention:

  • Security Hub Extended expands to 21 curated partner solutions across 9 categories — AWS Security Hub Extended now integrates with 21 curated partner security solutions spanning 9 categories, including endpoint protection, cloud security posture management, threat intelligence, and more. You can now get consolidated, prioritized security findings from a broader ecosystem of tools directly within Security Hub, without requiring custom integrations. This is particularly valuable for enterprise security teams that want a unified view of their security posture across AWS and third-party tooling.
  • Amazon SageMaker AI now supports OpenAI-compatible APIs for inference endpoints — You can now call Amazon SageMaker AI inference endpoints using OpenAI-compatible APIs, making it significantly easier to migrate AI workloads from OpenAI to SageMaker — or to build applications that work across multiple providers — with no SDK changes required. This lowers the migration barrier for teams that started prototyping with OpenAI and are now looking to move to a more scalable, cost-controlled infrastructure on AWS. Your existing application code works as-is; you simply point it at your SageMaker endpoint.
  • Introducing pre-fetching and IAM role assumption for AWS Secrets Manager Agent — The AWS Secrets Manager Agent can now pre-fetch secrets at startup and assume IAM roles to retrieve them, eliminating the cold-start latency associated with on-demand secret retrieval in latency-sensitive applications. You can configure the agent to preload the secrets your application needs before it starts serving traffic, reducing the risk of secrets-related latency spikes in production. IAM role assumption support also makes it easier to share the agent across workloads with different permission boundaries.
  • AWS announces ExtendDB, an open-source DynamoDB-compatible adapter — AWS has open-sourced ExtendDB, a DynamoDB-compatible adapter that allows you to use the DynamoDB API and data model on top of alternative backend storage systems. This is particularly useful for local development and testing workflows — you can write against the DynamoDB API without requiring a live AWS connection. It’s also valuable for scenarios where you need DynamoDB-compatible semantics with more control over the underlying storage layer. It’s a practical tool for teams that want to build portability into their data access layer.
  • AWS SAM CLI adds AWS CloudFormation Language Extensions support to accelerate local serverless development — The AWS SAM CLI now supports AWS CloudFormation Language Extensions locally, meaning you can use transforms, dynamic references, and other CloudFormation language features directly in your local development and testing workflows. This closes a long-standing gap between what you can test locally and what runs in production, making local serverless development faster and more reliable. If you build serverless applications with SAM and encounter edge cases in local testing, this update will meaningfully improve your experience.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Amazon Bedrock introduces new advanced prompt optimization and migration tool — This post covers the newly launched Advanced Prompt Optimization and Migration Tool in Amazon Bedrock, which helps you automatically tune your prompts for better model performance and assists you in migrating prompts across different foundation models. It’s a must-read if you’re iterating on prompt quality for production AI workloads.
  • Introducing Kiro Web — Kiro, AWS’s AI-powered development environment, now has a web-based interface. Kiro Web lets you access Kiro’s spec-driven development, AI chat, and agent capabilities directly from your browser, without needing to install the desktop IDE. This is a great step toward making AI-assisted development more accessible — whether you’re doing a quick review, prototyping from a new machine, or introducing your team to the Kiro workflow.
  • Announcing updated retry behavior for AWS SDKs and Tools — AWS has updated the default retry behavior across its SDKs and CLI tools, improving resilience for transient errors without requiring configuration changes from developers. The updated behavior includes smarter backoff strategies and better handling of throttling responses. If you’re running production workloads that occasionally hit API rate limits or transient failures, this update improves reliability out of the box. It’s worth reading to understand what changed and how it affects your applications.
  • Bitnami image removal from ECR Public — AWS has announced that Bitnami container images will be removed from Amazon ECR Public. If your workloads pull Bitnami images from ECR Public, you should review this post to understand the timeline and migration path. The Bitnami images remain available directly from Bitnami’s own registry, and this post explains how to update your image references to continue pulling them without interruption.

Upcoming AWS events
Check your calendar and sign up for these events:

  • AWS Summit Amsterdam — Join us in Amsterdam on May 27 for a full day of cloud and AI sessions, hands-on labs, and networking with builders and AWS experts from across Europe. Registration is free.
  • AWS Summit Bangkok — AWS Summit Bangkok takes place on May 28. It’s a fantastic opportunity for builders and customers across Southeast Asia to connect and explore the latest in cloud innovation.
  • AWS Summit Milan — Also on May 28, AWS Summit Milan brings the AWS community together in Italy. If you’re in Southern Europe, this is your event.
  • AWS Summit Mumbai — Also on May 28, AWS Summit Mumbai brings cloud and AI content to builders across India. Check the link for the full agenda and registration.
  • AWS Summit Los Angeles — Mark your calendar for June 10 in Los Angeles. The AWS Summit LA is coming up and it’s a great opportunity to connect with the West Coast builder community.
  • AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders. If you’re in Latin America, don’t miss AWS Community Day Belo Horizonte on August 22 — registration is open at awscommunityday.com.br.

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Daniel Abib

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS Security Hub Extended: Why enterprise security products should sell themselves

Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/aws-security-hub-extended-why-enterprise-security-products-should-sell-themselves/

Our largest security services customers started the same way every customer does – with a click. They enabled Amazon GuardDuty, Amazon Inspector, AWS WAF, and AWS Security Hub, experienced the benefits in real time, and evaluated with transparent pay-as-you-go pricing. No RFP. No six-month evaluation. No multi-year commitment up front. Our field teams played a critical role in that growth, not by selling the first click, but by building the trusted relationships that turned early adoption into deep, long-term commitment. We believe customers should have this same frictionless adoption experience and flexibility for all best-in-class security products and that’s why we developed Security Hub Extended.

In our first post, we introduced Security Hub Extended, a significant expansion of Security Hub that brings together curated partner solutions in a single, unified experience. In our second post, we walked through how it works technically, including the onboarding flow, the pricing model, the unified operations layer built on the Open Cybersecurity Schema Framework (OCSF). In this post, I want to step back and talk about why we built it the way we did and why I believe the way enterprises discover, evaluate, and adopt security solutions is ready for a fundamental shift.

The shift

If you’ve ever tried to evaluate a new enterprise security product, you know the drill. Request a demo. Wait. Take the demo. Request a PoC. Wait for professional services (or your team to stop building) to set it up. Negotiate pricing, which isn’t published, so you’re starting blind. Loop in procurement. Sign a multi-year commitment. Then, months later, find out whether the product actually solves your problem in your unique environment.

Meanwhile, an ambitious security engineer on your team has already spun up an open-source tool, connected real data, and knows in two hours whether it’s going to work for your use cases. They didn’t need a slide deck. They needed a solution they could put their hands on.

A Fortune 500 CISO recently told me: “I spent 9 months procuring a security solution and it still doesn’t work the way the demo showed.” That frustration isn’t unique. It’s the norm.

This isn’t a criticism of the sales motion. Sales-led has evolved for good reason. Enterprise procurement is complex, products need customization, customers need support. I respect the craft and have poured a significant portion of my career into trying to perfect it. Even the most product-driven companies still need great sales, marketing, field enablement, and support.

It doesn’t change the fact that threats are evolving constantly, and defenders need the flexibility to discover and deploy new solutions as fast as the landscape shifts. Having the best solutions discoverable and deployable in that moment of need isn’t just a convenience, it’s a competitive advantage that customers are demanding. A new threat emerges, security teams have access to industry-leading solutions, and in a few clicks they’ve found their answer and are already seeing value. That’s the model every security company should be building toward.

What we’ve learned at AWS

At AWS, we’ve spent two decades learning what it takes to let customers adopt complex enterprise technology on their own terms, at massive scale. We haven’t always gotten it right, but we learn fast and adjust. The result is one of the largest cloud businesses in the world. I bring up that scale for one reason. It’s proof that complex, enterprise-grade technology can be adopted without requiring a traditional procurement gauntlet. Compute, storage, databases, AI/ML, networking, and yes, security — adopted all through a console, on each customer’s own timeline, and scaled when they were ready.

The proof is in the adoption

Amazon GuardDuty, Amazon Inspector, AWS Shield, AWS Security Hub are all available through the AWS Management Console. All pay-as-you-go. All activated with a click. Tens of thousands of customers rely on these security services today. When you make it easy to get started and deliver outcomes that earn confidence, expansion follows naturally.

These are sophisticated, enterprise-grade security solutions. And customers, from two-person startups to the world’s largest financial institutions, adopt them the same way. They try it, see the value, expand, and lean on the AWS team to go deeper.

We didn’t get here by accident, and we definitely didn’t get here without making mistakes. Building products that can be adopted and scaled on their own, without a sales engineer explaining away UX problems, without a solutions architect doing the first deployment, requires a different kind of product mindset. Time-to-value becomes your most important metric. Onboarding friction becomes your biggest enemy. Transparent pricing becomes non-negotiable. It’s hard. We’ve gotten a lot wrong along the way. And we’re still iterating.

But the results are clear. When customers adopt based on experience rather than commitment, they don’t just stay, they expand. They bring their teams. They become advocates. I’ve spent 15 years at AWS, the last 10 building security services like GuardDuty and Security Hub. When we launch a new security service or major feature, we consistently see rapid organic adoption at a pace that would be impossible through traditional sales cycles alone. These products are built to deliver value the moment customers turn them on and we make that as easy as we possibly can. That’s the scale a product-led motion unlocks.

Security Hub Extended

So, we asked ourselves: why can’t we build a similar approach that can expand to include industry leading partner solutions? Why can’t the CrowdStrikes, the Splunks, the Zscalers, and the fast-growing innovators solving tomorrow’s problems like Cyera, Noma, and 7AI also reach customers with the same frictionless motion that AWS services enjoy? Why can’t a security team that discovers a new threat on Monday have a proven solution deployed and delivering value by Tuesday? Our partners have built incredible products. What they haven’t always had is an avenue to put those products directly in the hands of the customers who need them most, at the moment they need them, at scale, in a way that feels as natural as turning on an AWS service. Not by replacing how our partners build or sell, but by giving them infrastructure that lets their products speak for themselves.

That’s what Security Hub Extended is. Security teams already using Security Hub can discover curated partner solutions right alongside their AWS security services. One click to evaluate, one click to deploy, pay-as-you-go pricing on your existing AWS bill with Enterprise Discount Program (EDP) discounts automatically applied. No separate procurement cycle. No long-term commitments required. Start fast, validate at scale, and commit for deeper discounts when you’re ready, versus making a three-year bet based on a few months of testing.

For customers, industry-leading enterprise security solutions become as easy to adopt as GuardDuty or WAF. For our partners, Security Hub Extended is a growth channel where the product leads and the customer experience mirrors what we’ve spent 20 years building at AWS. For the industry, it’s an invitation to reimagine what the relationship between a security product and a security practitioner can look like when you remove the friction standing between them.

But Security Hub Extended isn’t just a simpler way to buy security products. It’s a unified solution. When a customer enables a solution through Extended, we’re working toward an experience where AWS handles the rest. Sensors that deploy automatically across Amazon EC2, Amazon EKS, and AWS Fargate workloads using the same mechanism that powers GuardDuty Runtime Monitoring. IAM roles that provision across a customer’s Organization in one click. Resource inventory is automated from day one – S3 buckets, databases, AI workloads – without manual work.

Once enabled, solutions in Security Hub Extended emit findings in OCSF, automatically aggregated in Security Hub alongside findings from GuardDuty, Amazon Inspector, and every other AWS security service. Security Hub applies risk scoring and correlated risk analytics across all of them. AWS-native and third-party findings together, weighted and prioritized as a single view of your security posture. For example, an endpoint detection from CrowdStrike, correlated with a credential theft in GuardDuty, and a data access event from Cyera, produces an attack path that none of those solutions can produce alone. The correlation uses AWS context (IAM topology, VPC exposure, resource criticality) to improve the context of each attack path for security analysts. Deploying a solution through Security Hub Extended doesn’t add another pane of glass. It deepens the intelligence of the one you already have.

We’re also building toward automated response. Customers will be able to opt in to pre-built playbooks that take action through AWS-native services when a threat is detected, such as isolating compromised resources, revoking credentials, or containing active threats. The goal is detect-to-respond in seconds, not the hours it takes to context-switch across five consoles and two ticketing systems.

Where we are and where we’re headed

We’re still in the first inning — or Day 1, as we like to say at Amazon. We launched in February 2026 with 14 partners, now 21, spanning endpoint, identity, email, network, data, browser, cloud, AI, and security operations, and we’re continuously working backwards from customers as we operationalize for scale. We are building this because our customers asked for it. We’re learning alongside our partners and customers every week, identifying what works, what needs improvement, where the friction still lives, and iterating quickly.

We’re building and delivering at the speed of our customers. That means shipping fast, iterating faster, and not waiting for perfection. We’re not where we want to be just yet, and we need your feedback to get us there. What’s encouraging is that our partners aren’t waiting to be asked. They’re investing in this alongside us. Not because we’re demanding it, but because they see the same thing we do, that companies that make it effortless for customers to get started are the ones that will win at scale.

The early signals are encouraging. Customer response has exceeded our expectations, and the feedback we hear most often is that the procurement simplification and flexibility of pay-as-you-go with public pricing alone, even before the unified operations and data normalization benefits, is a meaningful differentiator.

If you’re a security leader: Security Hub Extended is live now. Log into Security Hub, look for the Security Hub Extended Plan (or visit the Security Hub Extended Pricing Page), and explore what’s available for your use cases. Start with what solves your most urgent problem. Pay-as-you-go, no commitment. Your team will tell you if it’s working in days, not months.

The vision is bigger than what’s live today, and we’re iterating fast. Share your feedback on AWS re:Post for Security Hub, reach out through contact AWS Support, or connect with me directly.


Michael Fuller

Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.


Securing client confidentiality at scale: Automated data discovery and governed analytics for legal workloads

Post Syndicated from Rohan Kamat original https://aws.amazon.com/blogs/big-data/securing-client-confidentiality-at-scale-automated-data-discovery-and-governed-analytics-for-legal-workloads/

Automating data security and analytics for legal documents presents a unique challenge when your legal team stores documents with strong access controls, organized by client and matter, encrypted at rest, and governed by well-defined policies. But what happens when you want to run analytics across those repositories? The typical path is extracting content into separate data pipelines or third-party tools, which fragments your governance model and introduces new risks. Law firms and corporate legal departments operate under distinct obligations that make data governance non-negotiable. Attorney-client privilege, work product doctrine, and professional conduct rules impose strict duties around how client information is handled, accessed, and disclosed. Governance failure in this context isn’t just a compliance gap, it can result in privilege waiver, disqualification from representation, or disciplinary action.

Legal professionals use ethical walls, also called information barriers, as structural safeguards that prevent the flow of confidential information between teams within a firm that represent adverse or potentially conflicting interests. Professional conduct rules mandate these barriers, and failure to maintain them can result in firm disqualification, malpractice liability, or regulatory sanctions.

Privilege boundaries are equally critical. Attorney-client privilege and work product protection apply only when you properly control access to the underlying material. If you expose privileged documents or metadata about their contents to unauthorized individuals, you risk losing your privilege protection. When organizations fail to maintain reasonable controls over privileged material, courts might find that they have waived their privilege. You should therefore actively manage your access governance, not only as a security concern but as a legal preservation requirement.When you extract content into separate analytics systems or grant broader access than your matter structures support, you create pressure on both protections. You gain visibility but lose confidence in your controls.

In this post, we show you a reference architecture that automates sensitive data discovery across legal document repositories on Amazon Web Services (AWS), demonstrate how to capture structured findings as a compliance dataset, and guide you through building a governed analytics workspace that maintains your security boundaries. You walk away with a practical model for building security and analytics into the same lifecycle, without moving documents outside their system of record.

Analytics shouldn’t weaken governance

Most legal organizations have invested heavily in securing their document repositories. You store documents in structured storage, organized by client and matter. You access controls map to matter boundaries (the organizational and access structures that separate one client engagement from another). You establish retention and hold policies.The difficulty starts when teams want to analyze what’s inside those repositories. Running analytics typically means copying content into a separate system, standing up a new data pipeline, or granting broader access than existing matter structures support. Each of these steps introduces governance gaps. Manual reporting fills some of the void, but it doesn’t scale and can’t provide continuous visibility. What’s missing is a model where security controls and analytics reinforce each other, where the act of discovering sensitive data also produces the dataset that you use for reporting, and where governance applies once and carries through every downstream operation.

Automation addresses this by combining continuous sensitive data discovery with governed analytics, built on discovery metadata rather than document copies. This automated approach delivers four key advantages:

  • No document movement. Your files stay in their system of record. Analytics runs against structured discovery metadata, not document content, so governance boundaries remain intact.
  • Continuous discovery instead of manual scanning. Automated classification identifies regulated and sensitive information on an ongoing basis, replacing periodic manual reviews with on demand visibility.
  • Unified governance. You define matter-aligned access policies once, and they carry through from document storage to findings analytics and compliance reporting.
  • Built-in audit readiness. A durable record of discovery findings and remediation actions accumulates automatically over time, giving you structured evidence for client reviews and regulatory inquiries.

Reference Architecture

The following architecture shows how continuous discovery, governance, and compliance operations can work together without copying legal documents into analytics systems.

This reference architecture illustrates how law firms and corporate legal departments can automate sensitive data discovery and compliance analytics on AWS without moving documents outside their system of record

Architecture walkthrough

Store and protect documents in Amazon Simple Storage Service (Amazon S3)

Store your legal documents in Amazon S3, which serves as the system of record for document content. Align your buckets and prefixes to client and matter structures so that access controls map directly to matter boundaries. Where your retention or legal hold requirements demand it, apply S3 Object Lock to enforce immutability. You can encrypt your data using AWS Key Management Service (AWS KMS), which gives you centralized control over encryption keys and policies.

Discover and classify sensitive data with Amazon Macie

You will configure Amazon Macie to continuously analyze your document repositories. Macie identifies regulated information such as personally identifiable information (PII), financial data, and other sensitive content and produces structured findings that describe what Macie identified and where it exists. This provides ongoing visibility into data exposure without requiring document movement or manual scanning.

Catalog and govern findings with AWS Glue and AWS Lake Formation

You will use AWS Glue to catalog the findings dataset and maintain its schema so it stays query-ready. Apply AWS Lake Formation tag-based policies to govern access, aligning tags to client, matter, and confidentiality tier. This approach enforces ethical walls and least-privilege access consistently across analytics and reporting activities.

AI-powered chat agent using Amazon Quick Suite

You can create custom chat agents to tailor conversational interfaces for specific legal business needs. These agents can be configured with legal-specific knowledge bases, connected to relevant document repositories, and customized with instructions appropriate for legal workflows. You can use this chat agent to interact with your legal documents through natural language conversation for capabilities like:

  • E-Discovery:Search and analyze large volumes of legal documents to quickly find relevant information across your document repository.
  • Contract Analysis:Review contracts and automatically extract key terms, clauses, and obligations to streamline your contract review process.

The chat agent can help you navigate complex document sets through conversational queries, making legal research and document review more efficient and accessible.

Analyze and report with Amazon Quick Sight

You will use Amazon Quick as your compliance operations workspace. Quick provides a unified environment where your teams can query findings, generate dashboards, track remediation actions, and produce audit-ready reports. The agentic AI capabilities of Amazon Quick can autonomously build analyses, surface anomalies across matters, generate executive summaries for client reviews, and proactively recommend remediation priorities based on finding severity and trends. Combined with built-in data stories for automated narrative generation and pixel-perfect paginated reports for regulatory submissions, Quick reduces the time from discovery to action while keeping your teams within a governed interface aligned to matter-based permissions. Rather than switching between separate visualization, workflow, and reporting tools, your legal and compliance teams can review findings, manage response activities, and collaborate all within a single workspace that respects ethical walls and privilege boundaries.

Escalate high-severity findings

For high-severity findings that demand immediate attention, route alerts through AWS Security Hub or Amazon Simple Notification Service (Amazon SNS) to trigger escalation workflows. This connects visibility directly to action when your teams identify sensitive data risks.

Why this approach works for legal

Documents stay where they belong. Your files remain in Amazon S3, aligned to client and matter boundaries. No content moves into separate analytics pipelines.Ethical walls remain intact. Because analytics is built on discovery findings and not document copies, you can govern access to findings using the same matter-aligned controls that apply to documents. Compliance and security teams gain visibility without expanding document access.Discovery runs continuously, not periodically. Rather than scheduling quarterly or annual scans, you maintain a current view of sensitive data across your repositories.

Governance applies once and carries through. Lake Formation tag-based policies govern findings access at the catalog level. You define your matter and confidentiality mappings once, and they carry through to every dashboard, query, and report.Audit readiness is built in. Instead of assembling reports manually before a client review or regulatory inquiry, you maintain a historical record of discovery findings and remediation actions. You can demonstrate your posture over time with consistent, structured evidence.

Security and analytics reinforce each other. Your analytics capability is built on top of your security controls, not alongside them. Strengthening one strengthens the other.

Cost considerations

The primary cost drivers for this architecture include:

  • Amazon Macie: You pay based on the number of S3 buckets evaluated and the volume of data inspected for sensitive data discovery. Review Amazon Macie pricing for current rates.
  • Amazon S3: Storage costs for both your document repositories and the compliance intelligence bucket. Consider S3 lifecycle policies to tier older findings into lower-cost storage classes.
  • AWS Glue and AWS Lake Formation: Charges for crawlers and catalog storage. For most implementations, these costs are modest.
  • Amazon QuickSight: Per-user pricing based on the edition that you select (Standard or Enterprise). Enterprise edition supports row-level and column-level security, which aligns well with matter-based governance.
  • Amazon EventBridge, AWS Security Hub, and Amazon SNS: Charges based on event volume and notifications delivered. For findings-based workflows, these costs are generally low.

Use the AWS Pricing Calculator to estimate costs based on your repository size, user count, and discovery frequency.

Getting started

Start by identifying a representative set of document repositories in Amazon S3. We recommend that you start with two or three matters that span different practice areas and confidentiality tiers.

  1. Turn on Amazon Macie for those repositories and configure automated sensitive data discovery.
  2. Catalog the findings dataset with AWS Glue and apply Lake Formation tag-based access policies aligned to your matter structure.
  3. Build your first Amazon Quick Sight dashboard to visualize findings by matter, sensitivity type, and severity.
  4. Define escalation rules in AWS Security Hub or Amazon SNS for high-severity findings.

After you validate this workflow against your initial repositories, expand gradually. Add more repositories to Macie discovery. Refine your governance tags to reflect practice areas and confidentiality tiers. Extend your dashboards from basic posture visibility to trend analysis and remediation tracking.The goal isn’t to build a comprehensive analytics solution all at once. Start with a secure foundation where discovery findings, governance, and reporting operate together in a way that aligns with your legal workflows, and then expand from there.

Conclusion

You don’t have to choose between protecting client data and understanding it. By building analytics on top of governed discovery findings and using a unified compliance workspace, you gain visibility into your data posture without weakening confidentiality boundaries.This approach brings security, governance, and analytics together in a way that reflects how legal work is actually structured. It provides continuous visibility, supports audit readiness, and delivers insight without requiring documents to move outside their system of record.

Next steps

Review the Amazon Macie User Guide to understand sensitive data discovery configuration options and Amazon Quick Sight documentation to evaluate dashboard and row-level security capabilities.

Contact your AWS account team to discuss implementation support for legal and compliance workloads.


About the authors

Photo of Author - Rohan Kamat

Rohan Kamat

Rohan Kamat is a Solutions Architecture Leader within HCLS with extensive experience in cloud architecture, cybersecurity, Identity and Access Management, and enterprise networking. Rohan focuses on helping architects build both depth in cloud technologies and strength in executive communication, making sure they can confidently guide organizations through business and technical transformation. Outside of his professional work, Rohan enjoys time with his family, organizing community cricket events, and exploring fitness and wellness activities like pickleball and ping pong. He also enjoys planning travel experiences that bring people together and create lasting shared memories.

Photo of Author- Miguel Lopez Luis

Miguel Lopez Luis

Miguel Lopez Luis is an AWS Solutions Architect who works with small and medium businesses across the United States. He graduated with a Bachelor’s degree in Cybersecurity from Bellevue University in Nebraska and is a member of the Omega Nu Lambda Honor Society. Leveraging his extensive expertise in business management, Miguel is passionate about planning strategic initiatives, leading cross-functional teams, and mentoring others. In his personal time, he enjoys activities that involve travel, sports, and cooking.

Photo of Author - Pranali Khose

Pranali Khose

Pranali Khose is an AWS Solutions Architect based in Seattle. She works directly with small and medium business (SMB) customers across the United States, to design and implement cloud solutions that address their unique business challenges and accelerate digital transformation. Pranali holds a Master of Science in Computer Science from the University of Texas at Arlington.

Complimentary virtual training: Get hands-on with AWS Security Services

Post Syndicated from Ashley Nelson original https://aws.amazon.com/blogs/security/complimentary-virtual-training-get-hands-on-with-aws-security-services/

If you’re looking to strengthen your organization’s security posture on Amazon Web Services (AWS) but aren’t sure where to start, then we’re here to help. Security Activation Days are complimentary, virtual, hands-on workshops designed to help you get practical experience with AWS security services in a single session.

What to expect

Each Security Activation Day is a 3–6 hour virtual workshop where you work directly with AWS security services in real-world scenarios. Through a combination of presentations, demos, and workshops, you will get hands-on practice guided by AWS security specialists either in your own environment or in an AWS-provided sandbox.

Topics rotate across the full spectrum of AWS security, identity, and governance services, including threat detection and response, identity and access management, network and application protection, data protection, and governance and compliance. You will leave with actionable knowledge you can apply to your workloads immediately—not a to-do list of things to research later.

Who should attend

Security Activation Days are made for builders—security engineers, cloud architects, and DevOps teams who want to go deeper on specific AWS security capabilities. Whether you’re evaluating a service for the first time or looking to operationalize something you’ve already deployed, these sessions meet you where you are.

What attendees are saying

With over 6,400 attendees across 90 events so far in 2026, Security Activation Days consistently earn a 4.8 out of 5 satisfaction rating. Participants tell us the hands-on format is what makes the difference: there’s no substitute for actually configuring a service and seeing the results in real time.

How to register

We run Security Activation Days year-round across all time zones, with new sessions added regularly. Find a session, show up ready to learn, and start building today.

If you have feedback about this post, submit comments in the Comments section below.

Ashley Nelson

Ashley Nelson

Ashley is a Sr. WW Security Specialist at AWS, where she leads worldwide customer enablement programs for Security, Identity, and Governance services.

Security posture improvement in the AI era

Post Syndicated from Celeste Bishop original https://aws.amazon.com/blogs/security/security-posture-improvement-in-the-ai-era/

It’s only been a few weeks since Anthropic announced the Claude Mythos Preview model and launched Project Glasswing with AWS and other leading organizations. This has generated a lot of discussion about the future of cybersecurity and what the ever-increasing capabilities of foundation models mean to organizations.

As AWS CISO Amy Herzog pointed out in the Project Glasswing announcement, “At AWS, we build defenses before threats emerge, from our custom silicon up through the technology stack. Security isn’t a phase for us; it’s continuous and embedded in everything we do.”

Read more from Amy about this in Building AI defenses at scale: Before the threats emerge.

While the discussion around the future of cybersecurity is important, the only thing we know for certain is that organizations need to be able to react quickly to the rapid changes AI is bringing to technology and business in general. And you can’t react quickly if your security fundamentals aren’t dialed in.

The security hygiene gap

It’s easy to assume you have the foundational security elements covered, or to overlook some completely. Basic security use cases like identity management, threat detection, vulnerability management, data protection, and network security can be inconsistently implemented across cloud environments. While AI is reshaping the security landscape, strong security fundamentals continue to be essential for every organization, regardless of size or industry.

These are the security basics that matter whether or not you’re adopting AI: patching consistently, enforcing least-privilege access, enabling logging and monitoring, encrypting data at rest and in transit, and reviewing security configurations regularly. When these fundamentals are in place, you’re better positioned to take advantage of AI-driven tools and respond to newly discovered vulnerabilities, wherever they come from.

While the concepts that drive security fundamentals are universal, implementing them in your environment is best done with an understanding of the context unique to your organization. That’s why we have a multitude of freely available materials—like the AWS Well-Architected Framework—that you can use to help ask the right questions and implement changes in your environment. We also offer programs like the Security Health Improvement Program (SHIP) to help you improve your security posture through prescriptive guidance and continuous improvement.

What is the Security Health Improvement Program (SHIP)?

SHIP is a no-cost program available to every AWS customer, regardless of support tier. SHIP provides a proven, data-driven methodology to:

  • Assess your current security posture using data from your AWS environment
  • Identify specific opportunities to improve across 10 core security use cases
  • Build a prioritized action plan tailored to your environment
  • Establish a mechanism for continuous security improvement

The program is led by AWS Solutions Architects and Technical Account Managers who take you through a personalized report, contextualize findings for your environment, and help you build a prioritized action plan.

Why SHIP matters in the AI era

Project Glasswing highlights an important shift: AI-powered tools are accelerating the pace of vulnerability discovery, which means organizations need to be prepared to assess and respond to findings and changing situations faster than before. In addition to external factors, as organizations adopt AI—whether deploying foundation models, building agentic workflows, or using AI-powered services—how they implement their security controls must change as well. A strong security foundation is what makes confident AI adoption possible.

Here’s how SHIP helps:

Address foundational security gaps proactively

SHIP uses a data-driven methodology to identify opportunities to improve and optimize across 10 core security use cases: threat detection, cloud security posture management, application security testing, configuration management, access governance, vulnerability management, application protection, network security, encryption, and secrets management. The program includes a SHIP assessment to identify critical security findings related to your current security posture, so your team can build a prioritized roadmap for improvement tailored to your environment.

Establish the security baseline AI workloads require

Before you deploy your first model on Amazon Bedrock or build agentic workflows with Amazon Bedrock AgentCore, you need confidence that your underlying infrastructure follows security best practices. SHIP uses actual data from your environment to provide prescriptive, specific guidance rather than generic security recommendations. This is especially relevant as AI-driven vulnerability discovery tools become more widely available: organizations with strong baselines will be able to act on new findings quickly and effectively.

Build a mechanism for continuous security improvement

As AI capabilities evolve, organizations benefit from having a repeatable process to assess and strengthen their security posture over time. SHIP establishes the methodology and mechanisms for your team to continuously assess, prioritize, and improve. By building this operational capability, you’re strengthening your organization’s ability to adapt and contributing to broader industry resilience. As the cybersecurity community integrates AI into defense strategies, SHIP helps you maintain foundational best practices so you can adopt these innovations effectively and with confidence.

Getting started is straightforward

SHIP is available today, at no cost, to every AWS customer. Here’s how to get started:

  1. Talk to your AWS account team. Ask about scheduling a SHIP engagement, or request one directly on the SHIP page.
  2. Attend a SHIP Activation Day. AWS regularly hosts hands-on workshops where you can run the SHIP assessment with AWS Solutions Architects and start building your improvement plan.
  3. Explore the prescriptive guidance. Consult the AWS Well-Architected Framework – Security Lens for documentation, reference architectures, and implementation guides you can start using today.

Take the next step together

AWS is committed to being the most secure cloud, from our participation in Project Glasswing to the security embedded in every layer of our infrastructure. Security is a shared responsibility, and programs like SHIP give customers the tools, guidance, and support to strengthen their security foundations so they can build confidently, no matter what comes next.

Ready to improve your security posture? Contact your AWS account team to schedule a SHIP engagement, or visit the SHIP resources page to learn more.

Celeste Bishop

Celeste Bishop

Celeste is a Senior Security Specialist at AWS, based in Austin, Texas. Over the past five years, she has held a range of security-focused roles spanning field and product marketing, developer relations, and executive engagement. She partners closely with customers, security leaders, and field teams to help organizations operate securely in the cloud. Celeste holds a Bachelor’s in Economics from the University of Texas at Austin.

A technical walkthrough of multicloud full-stack security using AWS Security Hub Extended

Post Syndicated from Matt Meck original https://aws.amazon.com/blogs/security/a-technical-walkthrough-of-multicloud-full-stack-security-using-aws-security-hub-extended/

Building on our recent announcement of AWS Security Hub Extended —our full-stack enterprise security offering — we want to show you how we’re simplifying security procurement and operations for your multicloud environments. Whether you’re a security architect evaluating solutions or a CISO looking to streamline vendor management, this post walks through the streamlined experience that transforms how you acquire, deploy, and manage end-to-end enterprise security solutions across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. Security Hub Extended brings together AWS security services with carefully curated security partners. Delivering better outcomes together through unified procurement, billing, and operations that significantly reduce vendor management overhead so you can focus on what matters most: protecting your organization.

The challenge we’re addressing

Security teams today spend too much time on vendor management, evaluating services, negotiating contracts, and managing multiple billing cycles instead of focusing on what matters most: managing risk. But the procurement challenge runs even deeper. Until now, customers really only had one option: sign multi-year agreements based solely on proof-of-concept testing and estimated annual usage. This forces organizations to commit budget before they can validate whether a solution will work for them at scale.

AWS Security Hub Extended transforms this procurement model. Security Hub Extended offers customers the option to get started with pay-as-you-go pricing and no commitments, so they can move fast and validate solutions in their actual environment. After they’ve confirmed a solution works at scale, they can then align their vendor strategy and sign longer-term commitments for even more favorable pricing.

Security Hub Extended provides a curated set of carefully chosen partner solutions with competitive pricing, unified billing through your AWS account, and seamless integration. Our initial launch partners, selected by customers for their proven value, include 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk, Upwind, and Zscaler.

Getting started with Security Hub Extended

AWS Security Hub consolidates threat analytics from Amazon GuardDuty, vulnerability management from Amazon Inspector, and sensitive data discovery from Amazon Macie, correlating these signals with Security Hub Exposure findings to determine overall risk, reachability, and assumability. Security Hub Extended builds on this foundation by adding curated partner solutions, extending these unified security operations across your entire organization including multicloud, on-premises, and endpoint environments. If you’re already using Security Hub, you can navigate directly to the Extended plan section.

Getting started with Security Hub is straightforward. From the AWS Management Console, search for Security Hub to start the onboarding walkthrough. If you’re not already a Security Hub customer, you can quickly complete onboarding by designating an AWS organization delegated administrator (DA) account. You can then centrally enable and manage Security Hub across your entire organization’s accounts and AWS Regions from a single location (see Introduction to AWS Security Hub). After you’ve onboarded, navigate to the Extended plan section to add curated partner solutions.

Figure 1- Security Hub centralized configuration

Figure 1: Security Hub centralized configuration

From this single interface, you can enable detection and response capabilities across your entire organization, provide granular configurations at the organizational unit or member account level, select specific Regions, and turn individual features on or off as needed.

Understanding risk through attack paths

The Security Hub risk correlation engine identifies potential exposures by correlating threats, vulnerabilities, and misconfigurations to reveal how they connect and could lead to compromise of critical resources.

Figure 2 - Security Hub exposure attack path visualization

Figure 2: Security Hub exposure attack path visualization

The attack path visualization in the preceding figure reveals critical insights including upstream root causes and blast radius, showing the potential impact if a threat actor exploits a vulnerability. You can use this visualization to focus on fixing the root cause rather than addressing symptoms. For example, updating one security group configuration can eliminate the entire attack path, cutting off all downstream exposure.

Accessing Security Hub Extended

You can find Security Hub Extended, shown in the following figure, in the left navigation pane under Management in your Security Hub delegated administrator (DA) account; Security Hub Extended will only be visible from the delegated administrator account. The Extended plan brings curated third-party security solutions directly into the Security Hub experience. Because Extended is built into Security Hub, there’s no separate console to manage. You discover, subscribe to, and operate curated partner solutions from the same place you manage enterprise security, delivering unified operations across your entire security estate.

Figure 3- Security Hub Extended partners

Figure 3: Security Hub Extended partners


Transparent, competitive pricing consolidated with Security Hub

Unlike traditional third-party engagements that require lengthy negotiations, private pricing deals, and multi-year commitments, Security Hub Extended offers complete pricing transparency. Every partner solution displays clear, competitive monthly pay-as-you-go rates billed directly with Security Hub requiring no commitments. For example, Cloud Security from Upwind costs $3.75 per resource per month, and Identity Security from Okta costs $20 per user per month.

All Security Hub Extended offerings are also eligible for AWS Enterprise Discount Program (EDP) discounts that will be applied automatically. If you have an existing AWS enterprise discount agreement, those discounts automatically apply to Security Hub Extended offerings, further reducing your effective costs. All partner solutions you deploy through Security Hub Extended appear on your consolidated AWS bill, no separate invoices or payment processes.

Streamlined onboarding

Adopting curated partner solutions through Security Hub Extended is straightforward. Choose View Product to initiate an automated workflow. Depending on the solution, you’ll either be directed to the partner onboarding console or provide information for the partner to guide you through their onboarding process tailored to your environment.

Billing begins only after you’re fully activated on the partner solution and starts automatically, no additional action is required to benefit from the unified billing. If you’re already using one of the curated partner solutions, transitioning to Security Hub Extended for consolidated billing and flexible pricing won’t disrupt your current services. Now, instead of receiving separate invoices for each partner in addition to Amazon Inspector, GuardDuty, and Security Hub CSPM you get one unified bill through Security Hub. This consolidates visibility to support better understanding of spend and to manage cost.

Unified operations

Security Hub Extended unifies security operations by consolidating findings from AWS and curated partner solutions. All findings use the Open Cybersecurity Schema Framework (OCSF) for consistency, without the need for complex data normalization, transformation, and extract, transform, and load (ETL) processes.

When you deploy solutions such as CrowdStrike, Noma, and Upwind alongside Splunk and 7AI through Security Hub Extended, security findings automatically flow into Security Hub and then seamlessly route to Splunk and 7AI. All in OCSF format so your security team can focus on responding to threats, not managing pipelines, so you can quickly identify and respond to security risks that span boundaries—from endpoint compromises to cloud infrastructure—without spending valuable time on manual integration work.

The full-stack security vision

Security Hub Extended represents a shift in how you discover, procure, and build comprehensive security programs. Instead of managing dozens of vendor relationships, negotiating separate contracts, agreeing to multi-year annual commitments, and integrating disparate tools, you now have one procurement process through AWS, one bill with transparent competitive pay-as-you-go pricing, one console for unified security operations, one support channel for AWS Enterprise Support customers, and one schema (OCSF) for all security findings. The result: reduced security risk, improved team productivity, and a more unified approach to security operations across your enterprise.

Get started

Try Security Hub Extended today and experience how simplified procurement and unified operations can transform your security program. Security Hub Extended is generally available globally in all AWS commercial Regions where Security Hub is available. We’ve also published a walk through video to further explain how Security Hub Extended works.

It’s still Day 1, but we’re iterating fast, so share your feedback with us on AWS re:Post for Security Hub or through your AWS Support contacts and watch for future blog posts on our progress.


Matt Meck

Matt Meck

Matt is a Worldwide Security Specialist at Amazon Web Services, based in New York, with 10 years of experience in the tech industry. For the past 4 years at AWS, he’s focused on Detection and Response, helping solve complex security challenges in the rapidly evolving security space. He works closely with product teams, customers, partners, and field teams to deliver effective security solutions.


Michael Fuller

Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.


AWS Security Hub is expanding to unify security operations across multicloud environments

Post Syndicated from Gee Rittenhouse original https://aws.amazon.com/blogs/security/aws-security-hub-is-expanding-to-unify-security-operations-across-multicloud-environments/

After talking with many customers, one thing is clear: the security challenge has not gotten easier. Enterprises today operate across a complex mix of environments, including on-premises infrastructure, private data centers, and multiple clouds, often with tools that were never designed to work together. The result is enterprise security teams spend more time managing tools than managing risk, making it harder to stay ahead of threats across an increasingly complex environment.

At Amazon Web Service (AWS), we believe security should be simple, integrated, and built for the way enterprises actually operate. This belief is what drove us to reimagine AWS Security Hub, delivering full-stack security through a single experience, and this vision is driving our next chapter.

Building on a foundation of unified security

We transformed Security Hub into a unified security operations solution by bringing together AWS security services, including Amazon GuardDuty, Amazon Inspector, AWS Security Hub Cloud Security Posture Management (Security Hub CSPM), and Amazon Macie, into a single experience that automatically and continuously analyzes security signals across threats, vulnerabilities, misconfigurations, and sensitive data. Security Hub delivers a common foundation, bringing together findings from across your AWS environment so your security team spends less time translating signals and more time acting on them. Built on top of that foundation, a unified operations layer gives security teams near real-time risk analytics, automated analysis, and prioritized insights, helping them focus on what matters most, at scale.

We also introduced new capabilities (the Extended plan) that simplify how enterprises procure, deploy, and integrate a full-stack security solution across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. Now, customers can use Security Hub to expand their security portfolio through a curated selection of AWS Partner solutions (at launch: 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk (a Cisco company), Upwind, and Zscaler), all through one unified experience. With AWS as the seller of record, you benefit from pay-as-you-go pricing, a single bill, and no long-term commitments. Our goal is simple: unified security, everywhere your enterprise operates.

Freedom to innovate, wherever your workloads are

At AWS, interoperability means giving customers the freedom to choose solutions that best suit their needs, and the ability to use them wherever their workloads run. But freedom to innovate across multicloud environments also means that it is critical to secure them consistently, and without adding operational complexity.

What’s coming for Security Hub

In the coming months, we are expanding Security Hub with new multicloud capabilities that extend unified security operations beyond AWS. The foundation of this expansion is a common data layer that unifies security signals from wherever your workloads run. On top of that, a unified policy and operations layer delivers consistent posture management, exposure analysis, and risk prioritization, so your security team operates from a single view of risk rather than a fragmented collection of consoles.

Security Hub will deliver unified risk analytics that surface critical risks across your multicloud estate. You’ll be able to manage cloud security posture with Security Hub CSPM checks that give you consistent posture visibility, and extend vulnerability management with expanded Amazon Inspector capabilities, including virtual machine scanning, container image scanning, and serverless scanning. Security Hub will also deliver external network scanning that enriches security findings with context about internet-facing exposure across your multicloud environment, including for resources not running in AWS.

The result is more comprehensive risk coverage across your enterprise. It’s about giving your security team a single, unified experience to detect and respond to risks, wherever you operate.

Security as a business enabler

The security leaders I speak with aren’t just asking for better tools. They’re asking for a way to get ahead of risk, not just manage it. They want security that keeps pace with the business, not security that slows it down.

That’s the vision behind AWS Security Hub: unified security through a single, integrated security operations experience, built on a common data foundation, powered by intelligent analytics, and delivered through a consistent operations layer, to help reduce security risk, improve team productivity, and strengthen security operations across AWS and beyond.

Our multicloud expansion is underway, and we are just getting started.

You can learn more at aws.amazon.com/security-hub, or visit us at the AWS booth (S-0466) at RSA Conference, March 23–26 in San Francisco.

Gee Rittenhouse
Gee Rittenhouse

Gee is the Vice President of Security Services at AWS, overseeing key services including Security Hub, GuardDuty, and Inspector. He holds a PhD from MIT and brings extensive leadership experience across enterprise security and cloud. He previously served as CEO of Skyhigh Security and Senior Vice President and General Manager of Cisco’s Security Business Group, where he was responsible for Cisco’s worldwide cybersecurity business.

AWS Weekly Roundup: OpenAI partnership, AWS Elemental Inference, Strands Labs, and more (March 2, 2026)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-openai-partnership-aws-elemental-inference-strands-labs-and-more-march-2-2026/

This past week, I’ve been deep in the trenches helping customers transform their businesses through AI-DLC (AI-Driven Lifecycle) workshops. Throughout 2026, I’ve had the privilege of facilitating these sessions for numerous customers, guiding them through a structured framework that helps organizations identify, prioritize, and implement AI use cases that deliver measurable business value.

Screenshot of GenAI Developer Hour

AI-DLC is a methodology that takes companies from AI experimentation to production-ready solutions by aligning technical capabilities with business outcomes. If you’re interested in learning more, check out this blog post that dives deeper into the framework, or watch as Riya Dani teaches me all about AI-DLC on our recent GenAI Developer Hour livestream!

Now, let’s get into this week’s AWS news…

OpenAI and Amazon announced a multi-year strategic partnership to accelerate AI innovation for enterprises, startups, and end consumers around the world. Amazon will invest $50 billion in OpenAI, starting with an initial $15 billion investment and followed by another $35 billion in the coming months when certain conditions are met. AWS and OpenAI are co-creating a Stateful Runtime Environment powered by OpenAI models, available through Amazon Bedrock, which allows developers to keep context, remember prior work, work across software tools and data sources, and access compute.

AWS will serve as the exclusive third-party cloud distribution provider for OpenAI Frontier, enabling organizations to build, deploy, and manage teams of AI agents. OpenAI and AWS are expanding their existing $38 billion multi-year agreement by $100 billion over 8 years, with OpenAI committing to consume approximately 2 gigawatts of Trainium capacity, spanning both Trainium3 and next-generation Trainium4 chips.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • AWS Security Hub Extended offers full-stack enterprise security with curated partner solutions — AWS launched Security Hub Extended, a plan that simplifies procurement, deployment, and integration of full-stack enterprise security solutions including 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk, Upwind, and Zscaler. With AWS as the seller of record, customers benefit from pre-negotiated pay-as-you-go pricing, a single bill, no long-term commitments, unified security operations within Security Hub, and unified Level 1 support for AWS Enterprise Support customers.
  • Transform live video for mobile audiences with AWS Elemental Inference — AWS launched Elemental Inference, a fully managed AI service that automatically transforms live and on-demand video for mobile and social platforms in real time. The service uses AI-powered cropping to create vertical formats optimized for TikTok, Instagram Reels, and YouTube Shorts, and automatically extracts highlight clips with 6-10 second latency. Beta testing showed large media companies achieved 34% or more savings on AI-powered live video workflows. Deep dive into the Fox Sports implementation.
  • MediaConvert introduces new video probe API — AWS Elemental MediaConvert introduced a free Probe API for quick metadata analysis of media files, reading header metadata to return codec specifications, pixel formats, and color space details without processing video content.
  • OpenAI-compatible Projects API in Amazon Bedrock — Projects API provides application-level isolation for your generative AI workloads using OpenAI-compatible APIs in the Mantle inference engine in Amazon Bedrock. You can organize and manage your AI applications with improved access control, cost tracking, and observability across your organization.
  • Amazon Location Service introduces LLM Context — Amazon Location launched curated AI Agent context as a Kiro power, Claude Code plugin, and agent skill in the open Agent Skills format, improving code accuracy and accelerating feature implementation for location-based capabilities.
  • Amazon EKS Node Monitoring Agent is now open source — The Amazon EKS Node Monitoring Agent is now open source on GitHub, allowing visibility into implementation, customization, and community contributions.
  • AWS AppConfig integrates with New Relic — AWS AppConfig launched integration with New Relic Workflow Automation for automated, intelligent rollbacks during feature flag deployments, reducing detection-to-remediation time from minutes to seconds.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

From AWS community
Here are my personal favorite posts from AWS community:

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.
  • AWS Summits — Join AWS Summits in 2026, free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
  • AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include JAWS Days in Tokyo (March 7), Chennai (March 7), Slovakia (March 11), and Pune (March 21).

Browse here for upcoming AWS led in-person and virtual events, startup events, and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!


AWS Security Hub Extended offers full-stack enterprise security with curated partner solutions

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-security-hub-extended-offers-full-stack-enterprise-security-with-curated-partner-solutions/

At re:Invent 2025, we introduced a completely re-imagined AWS Security Hub that unifies AWS security services, including Amazon GuardDuty and Amazon Inspector into a single experience. This unified experience automatically and continuously analyzes security findings in combination to help you prioritize and respond to your critical security risks.

Today, we’re announcing AWS Security Hub Extended, a plan of Security Hub that simplifies how you procure, deploy, and integrate a full-stack enterprise security solution across endpoint, identity, email, network, data, browser, cloud, AI, and security operations. With the Extended plan, you can expand your security portfolio beyond AWS to help protect your enterprise estate through a curated selection of AWS Partner solutions, including 7AI, Britive, CrowdStrike, Cyera, Island, Noma, Okta, Oligo, Opti, Proofpoint, SailPoint, Splunk, a Cisco company, Upwind, and Zscaler.

With AWS as the seller of record, you benefit from pre-negotiated pay-as-you-go pricing, a single bill, and no long-term commitments. You can also get unified security operations experience within Security Hub and unified Level 1 support for AWS Enterprise Support customers. You told us that managing multiple procurement cycles and vendor negotiations was creating unnecessary complexity, costing you time and resources. In response, we’ve curated these partner offerings for you to establish more comprehensive protection across your entire technology stack through a single, simplified experience.

Security findings from all participating solutions are emitted in the Open Cybersecurity Schema Framework (OCSF) schema and automatically aggregated in AWS Security Hub. With the Extended plan, you can combine AWS and partner security solutions to quickly identify and respond to risks that span boundaries.

The Security Hub Extended plan in action
You can access the partner solutions directly within the Security Hub console by selecting Extended plan under the Management menu. From there, you can review and deploy any combination of curated and partner offerings.

You can review details of each partner offering directly in the Security Hub console and subscribe. When you subscribe, you’ll be directed to an automated on-boarding experience from each partner. Once onboarded, consumption-based metering is automatic and you are billed monthly as part of your Security Hub bill.

Security findings from all solutions are automatically consolidated in AWS Security Hub. This gives you immediate and direct access to all security findings in normalized OCSF schema.

To learn more about how to enhance your security posture with these integrations for AWS Security Hub, visit the AWS Security Hub User Guide.

Now available
The AWS Security Hub Extended plan is now generally available in all AWS commercial Regions where Security Hub is available. You can use flexible pay-as-you-go or flat-rate pricing—no upfront investments or long-term commitments required. For more information about pricing, visit the AWS Security Hub pricing page.

Give it a try today in the Security Hub console and send feedback to AWS re:Post for Security Hub or through your usual AWS Support contacts.

Channy

File integrity monitoring with AWS Systems Manager and Amazon Security Lake 

Post Syndicated from Adam Nemeth original https://aws.amazon.com/blogs/security/file-integrity-monitoring-with-aws-systems-manager-and-amazon-security-lake/

Customers need solutions to track inventory data such as files and software across Amazon Elastic Compute Cloud (Amazon EC2) instances, detect unauthorized changes, and integrate alerts into their existing security workflows.

In this blog post, I walk you through a highly scalable serverless file integrity monitoring solution. It uses AWS Systems Manager Inventory to collect file metadata from Amazon EC2 instances. The metadata is sent through the Systems Manager Resource Data Sync feature to a versioned Amazon Simple Storage Service (Amazon S3) bucket, storing one inventory object for each EC2 instance. Each time a new object is created in Amazon S3, an Amazon S3 Event Notification triggers a custom AWS Lambda function. This Lambda function compares the latest inventory version with the previous one to detect file changes. If a file that isn’t expected to change has been created, modified, or deleted, the function creates an actionable finding in AWS Security Hub. Findings are then ingested by Amazon Security Lake in a standard OCSF format, which centralizes and normalizes the data. Finally, the data can be analyzed using Amazon Athena for one-time queries, or by building visual dashboards with Amazon QuickSight and Amazon OpenSearch Service. Figure 1 summarizes this flow:

Figure 1: File integrity monitoring workflow

Figure 1: File integrity monitoring workflow

This integration offers an alternative to the default AWS Config and Security Hub integration, which relies on limited data (for example, no file modification timestamps). The solution presented in this post provides control and flexibility to implement custom logic tailored to your operational needs and support security-related efforts.

This flexible solution can also be used with other Systems Manager Inventory metadata, such as installed applications, network configurations, or Windows registry entries, enabling custom detection logic across a wide range of operational and security use cases.

Now let’s build the file integrity monitoring solution.

Prerequisites

Before you get started, you need an AWS account with permissions to create and manage AWS resources such as Amazon EC2, AWS Systems Manager, Amazon S3, and Lambda.

Step 1: Start an EC2 instance

Start by launching an EC2 instance and creating a file that you will later modify to simulate an unauthorized change.

Create an AWS Identity and Access Management (IAM) role to allow the EC2 instance to communicate with Systems Manager:

  1. Open the AWS Management Console and go to IAM, choose Roles from the navigation pane, and then choose Create role.
  2. Under Trusted entity type, select AWS service, select EC2 as the use case, and choose Next.
  3. On the Add permissions page, search for and select the AmazonSSMManagedInstanceCore IAM policy, then choose Next.
  4. Enter SSMAccessRole as the role name and choose Create role.
  5. The new SSMAccessRole should now appear in your list of IAM roles:
Figure 2: Create an IAM role for communication with Systems Manager

Figure 2: Create an IAM role for communication with Systems Manager

Start an EC2 instance:

  1. Open the Amazon EC2 console and choose Launch Instance.
  2. Enter a Name, keep the default Linux Amazon Machine Image (AMI), and select an Instance type (for example, t3.micro).
  3. Under Advanced details:
    1. IAM instance profile, select the previously created SSMAccessRole
    2. Create a fictitious payment application configuration file in the /etc/paymentapp/ folder on the EC2 instance. Later, you will modify it to demonstrate a file-change event for integrity monitoring. To create this file during EC2 startup, copy and paste the following script into User data.
#!/bin/bash
mkdir -p /etc/paymentapp
echo "db_password=initial123" > /etc/paymentapp/config.yaml

Figure 3: Adding the application configuration file

Figure 3: Adding the application configuration file

  1. Leave the remaining settings as default, choose Proceed without key pair, and then select Launch Instance. A key pair isn’t required for this demo because you use Session Manager for access.

Step 2: Enable Security Hub and Security Lake

If Security Hub and Security Lake are already enabled, you can skip to Step 3.
To start, enable Security Hub, which collects and aggregates security findings. AWS Security Hub CSPM adds continuous monitoring and automated checks against best practices.

  1. Open the Security Hub console.
  2. Choose Security Hub CSPM from the navigation pane and then select Enable AWS Security Hub CSPM and choose Enable Security Hub CSPM at the bottom of the page.

Note: For this demo, you don’t need the Security standards options and can clear them.

Figure 4: Enable Security Hub CSP

Figure 4: Enable Security Hub CSP

Next, activate Security Lake to start collecting actionable findings from Security Hub:

  1. Open the Amazon Security Lake console and choose Get Started.
  2. Under Data sources, select Ingest specific AWS sources.
  3. Under Log and event sources, select Security Hub (you will use this only for this demo):
Figure 5: Select log and event sources

Figure 5: Select log and event sources

  1. Under Select Regions, choose Specific Regions and make sure you select the AWS Region that you’re using.
  2. Use the default option to Create and use a new service role.
  3. Choose Next and Next again, then choose Create.

Step 3: Configure Systems Manager Inventory and sync to Amazon S3

With Security Hub and Security Lake enabled, the next step is to enable Systems Manager Inventory to collect file metadata and configure a Resource Data Sync to export this data to S3 for analysis.

  1. Create an S3 bucket by carefully following the instructions in the section To create and configure an Amazon S3 bucket for resource data sync.
  2. After you created the bucket, enable versioning in the Amazon S3 console by opening the bucket’s Properties tab, choosing Edit under Bucket Versioning, selecting Enable, and saving your changes. Versioning causes each new inventory snapshot to be saved as a separate version, so that you can track file changes over time.

Note: In production, enable S3 server access logging on the inventory bucket to keep an audit trail of access requests, enforce HTTPS-only access, and enable CloudTrail data events for S3 to record who accessed or modified inventory files.

The next step is to enable Systems Manager Inventory and set up the resource data sync:

  1. In the Systems Manager console, go to Fleet Manager, choose Account management, and select Set up inventory.
  2. Keep the default values but deselect every inventory type except File. Set a Path to limit collection to the files relevant for this demo and your security requirements. Under File, set the Path to: /etc/paymentapp/.
Figure 6: Set the parameters and path

Figure 6: Set the parameters and path

  1. Choose Setup Inventory.
  2. In Fleet Manager, choose Account management and select Resource Data Syncs.
  3. Choose Create resource data sync, enter a Sync name, and enter the name of the versioned S3 bucket you created earlier.
  4. Select This Region and then choose Create.

Step 4: Implement the Lambda function

Next, complete the setup to detect changes and create findings. Each time Systems Manager Inventory writes a new object to Amazon S3, an S3 Event Notification triggers a Lambda function that compares the latest and previous object versions. If it finds created, modified, or deleted files, it creates a security finding. To accomplish this, you will create the Lambda function, set its environment variables, add the helper layer, and attach the required permissions.

The following is an example finding generated in AWS Security Finding Format (ASFF) and sent to Security Hub. In this example, you see a notification about a file change on the EC2 instance listed under the Resources section.

{
	...
"Id": "fim-i-0b8f40f4de065deba-2025-07-12T13:48:31.741Z",
	"AwsAccountId": "XXXXXXXXXXXX",
	"Types": [
		"Software and Configuration Checks/File Integrity Monitoring"
	],
	"Severity": {
		"Label": "MEDIUM"
	},
	"Title": "File changes detected via SSM Inventory",
	"Description": "0 created, 1 modified, 0 deleted file(s) on instance i-0b8f40f4de065deba",
	"Resources": [
		{
			"Type": "AwsEc2Instance",
			"Id": "i-0b8f40f4de065deba"
		}
	],
	...
}

Create the Lambda function

This function detects file changes, reports findings, and removes unused Amazon S3 object versions to reduce costs.

  1. Open the Lambda console and choose Create function in the navigation pane.
  2. For Function Name enter fim-change-detector.
  3. Select Author from scratch, enter a function name, select the latest Python runtime, and choose Create function.
  4. On the Code tab, paste the following main function and choose Deploy.
import boto3, os, json, re
from datetime import datetime, UTC
from urllib.parse import unquote_plus
from helpers import is_critical, load_file_metadata, is_modified, extract_instance_id

s3 = boto3.client('s3')
securityhub = boto3.client('securityhub')

CRITICAL_FILE_PATTERNS = os.environ["CRITICAL_FILE_PATTERNS"].split(",")
SEVERITY_LABEL = os.environ["SEVERITY_LABEL"]
	
def lambda_handler(event, context):
	# Safe event handling
	if "Records" not in event or not event["Records"]:
		return

	# Extract S3 event
	record = event['Records'][0]
	bucket = record['s3']['bucket']['name']
	key = unquote_plus(record['s3']['object']['key'])
	current_version = record['s3']['object'].get('versionId')
	if not current_version:
		return

	# Fetching the region name
	account_id = context.invoked_function_arn.split(":")[4]
	region = boto3.session.Session().region_name

	# Get object versions (latest first)
	versions = s3.list_object_versions(Bucket=bucket, Prefix=key).get('Versions', [])
	versions = sorted(versions, key=lambda v: v['LastModified'], reverse=True)

	# Find previous version
	idx = next((i for i,v in enumerate(versions) if v["VersionId"] == current_version), None)
	if idx is None or idx + 1 >= len(versions):
		return
	prev_version = versions[idx+1]["VersionId"]

	# Load both versions
	current = load_file_metadata(bucket, key, current_version)
	previous = load_file_metadata(bucket, key, prev_version)

	# Compare
	created = {p for p in set(current) - set(previous) if is_critical(p)}
	deleted = {p for p in set(previous) - set(current) if is_critical(p)}
	modified = {p for p in set(current) & set(previous) if is_critical(p) and is_modified(p, current, previous)}

	# Report if changes were found
	if created or deleted or modified:
		instance_id = extract_instance_id(bucket, key, current_version)
		now = datetime.now(UTC).isoformat(timespec='milliseconds').replace('+00:00', 'Z')
		finding = {
			"SchemaVersion": "2018-10-08",
			"Id": f"fim-{instance_id}-{now}",
			"ProductArn": f"arn:aws:securityhub:{region}:{account_id}:product/{account_id}/default",
			"AwsAccountId": account_id,
			"GeneratorId": "ssm-inventory-fim",
			"CreatedAt": now,
			"UpdatedAt": now,
			"Types": ["Software and Configuration Checks/File Integrity Monitoring"],
			"Severity": {"Label": SEVERITY_LABEL},
			"Title": "File changes detected via SSM Inventory",
			"Description": (
				f"{len(created)} created, {len(modified)} modified, "
				f"{len(deleted)} deleted file(s) on instance {instance_id}"
			),
			"Resources": [{"Type": "AwsEc2Instance", "Id": instance_id}]
		}
		securityhub.batch_import_findings(Findings=[finding])

	# No change – delete older S3 version
	else:
		if prev_version != current_version:
			try:
				s3.delete_object(Bucket=bucket, Key=key, VersionId=prev_version)
			except Exception as e:
				print(f"Delete previous S3 object version failed: {e}")

Note: In production, set Lambda reserved concurrency to prevent unbounded scaling, configure a dead letter queue (DLQ) to capture failed invocations, and optionally attach the function to an Amazon VPC for network isolation.

Configure environment variables

Configure the two required environment variables in the Lambda console. These two variables (one for critical paths to monitor and one for security finding severity) must be set or the function will fail.

  1. Open the Lambda console and choose Configuration and then select Environment variables.
  2. Choose Edit and then choose Add environment variable.
  3. Under Key, choose CRITICAL_FILE_PATTERNS
    1. Enter ^/etc/paymentapp/config.*$ as the value.
    2. Set the SEVERITY_LABEL to MEDIUM.
Figure 7: CRITICAL_FILE_PATTERNS and SEVERITY_LABEL configuration

Figure 7: CRITICAL_FILE_PATTERNS and SEVERITY_LABEL configuration

Set up permissions

The next step is to attach permissions to the Lambda function

  1. In your Lambda function, choose Configuration and then select Permissions.
  2. Under Execution role, select the role name that will lead to the role in IAM.
  3. Choose Add permissions and select Create inline policy. Select JSON view.
  4. Paste the following policy, and make sure to replace <bucket-name> with the name of your S3 bucket, and you also update <region> and <account-id> with your AWS Region and Account ID:
{
"Version": "2012-10-17",
"Statement": [
	{
		"Effect": "Allow",
		"Action": "securityhub:BatchImportFindings",
		"Resource": "arn:aws:securityhub:<region>:<account-id>:product/<account-id>/default"
	},
	{
		"Effect": "Allow",
		"Action": [
			"s3:GetObject",
			"s3:GetObjectVersion",
			"s3:ListBucketVersions",
			"s3:DeleteObjectVersion"
		],
		"Resource": [
			"arn:aws:s3:::<bucket-name>",
			"arn:aws:s3:::<bucket-name>/*"
			]
		}
	]
}

  1. To finalize, enter a Policy name and choose Create policy.

Add functions to the Lambda layer

For better modularity, add some helper functions to a Lambda layer. These functions are already referenced in the import section of the preceding Lambda function’s Python code. The helper functions check critical paths, load file metadata, compare modification times, and extract the EC2 instance ID.

Open AWS CloudShell from the top-right corner of the AWS console header, then copy and paste the following script and press Enter. It creates the helper layer and attaches it to your Lambda function.

#!/bin/bash
set -e
FUNCTION_NAME="fim-change-detector"
LAYER_NAME="fim-change-detector-layer"

mkdir -p python
cat > python/helpers.py << 'EOF'
import json, re, os
from dateutil.parser import parse as parse_dt
import boto3
s3 = boto3.client('s3')
CRITICAL_FILE_PATTERNS = os.environ.get("CRITICAL_FILE_PATTERNS", "").split(",")

def is_critical(path):
	return any(re.match(p.strip(), path) for p in CRITICAL_FILE_PATTERNS if p.strip())

def load_file_metadata(bucket, key, version_id):
	obj = s3.get_object(Bucket=bucket, Key=key, VersionId=version_id)
	data = {}
	for line in obj['Body'].read().decode().splitlines():
		if line.strip():
			i = json.loads(line)
			n, d, m = i.get("Name","").strip(), i.get("InstalledDir","").strip(), i.get("ModificationTime","").strip()
			if n and d and m: data[f"{d.rstrip('/')}/{n}"] = m
	return data

def is_modified(path, current, previous):
	try: return parse_dt(current[path]) != parse_dt(previous[path])
	except: return current[path] != previous[path]

def extract_instance_id(bucket, key, version_id):
	obj = s3.get_object(Bucket=bucket, Key=key, VersionId=version_id)
	for line in obj['Body'].read().decode().splitlines():
		if line.strip():
			r = json.loads(line)
			if "resourceId" in r: return r["resourceId"]
	return None
EOF

zip -r helpers_layer.zip python >/dev/null
LAYER_VERSION_ARN=$(aws lambda publish-layer-version \
	--layer-name "$LAYER_NAME" \
	--description "Helper functions for File Integrity Monitoring" \
	--zip-file fileb://helpers_layer.zip \
	--compatible-runtimes python3.13 \
	--query 'LayerVersionArn' \
	--output text)

aws lambda update-function-configuration \
	--function-name "$FUNCTION_NAME" \
	--layers "$LAYER_VERSION_ARN" >/dev/null
echo "Layer created and attached to the Lambda function."

Step 5: Set up S3 Event Notifications

Finally, set up S3 Event Notifications to trigger the Lambda function when new inventory data arrives.

  1. Open the S3 console and select the Systems Manager Inventory bucket that you created.
  2. Choose Properties and select Event notifications.
  3. Choose Create event notification.
    1. Enter an Event name.
    2. In the Prefix field, enter AWS%3AFile/ to limit Lambda triggers to file inventory objects only.
      Note: The prefix contains a : character, which must be URL-encoded as %3A.
    3. Under Event types, select Put.
    4. At the bottom, select your newly created Lambda function, and choose Save changes.

In this example, inventory collection runs every 30 minutes (48 times each day) but can be adjusted based on security requirements to optimize costs. The Lambda function is triggered once for each instance whenever a new inventory object is created. You can further reduce event volume by filtering EC2 instances through S3 Event Notification prefixes, enabling focused monitoring of high-value instances.

Step 6: Test the file change detection flow

Now that the EC2 instance is running and the sample configuration file /etc/paymentapp/config.yaml has been initialized, you’re ready to simulate an unauthorized change to test the file integrity monitoring setup.

  1. Open the Systems Manager console.
  2. Go to Session Manager and choose Start session.
  3. Select your EC2 instance and choose Start Session.
  4. Run the following command to modify the file:

echo “db_password=hacked456" | sudo tee /etc/paymentapp/config.yaml

This simulates a configuration tampering event. During the next Systems Manager Inventory run, the updated metadata will be saved to Amazon S3.

To manually trigger this:

  1. Open the Systems Manager console and choose State Manager.
  2. Select your association and choose Apply association now to start the inventory update.
  3. After the association status changes to Success, check your SSM Inventory S3 bucket in the AWS:File folder and review the inventory object and its versions.
  4. Open the Security Hub console and choose Findings. After a short delay, you should see a new finding like the one shown in Figure 8:
Figure 8: View file change findings

Figure 8: View file change findings

Step 7: Query and visualize findings

While Security Hub provides a centralized view of findings, you can deepen your analysis using Amazon Athena to run SQL queries directly on the normalized Security Lake data in Amazon S3. This data follows the Open Cybersecurity Schema Framework (OCSF), which is a vendor-neutral standard that simplifies integration and analysis of security data across different tools and services.

The following is an example Athena query:

SELECT
	finding_info.desc AS description,
	class_uid AS class_id,
	severity AS severity_label,
	type_name AS finding_type,
	time_dt AS event_time,
	region,
	accountid
FROM amazon_security_lake_table_us_east_1_sh_findings_2_0

Note: Be sure to adjust the FROM clause for other Regions. Security Lake processes findings before they appear in Athena, so expect a short delay between ingestion and data availability.
You will see a similar result for the preceding query, shown in Figure 9:

Figure 9: Athena query result in the Amazon Athena query editor

Figure 9: Athena query result in the Amazon Athena query editor

Security Lake classifies this finding as an OCSF 2004 Class, Detection Finding. You can explore the full schema definitions at OCSF Categories. For more query examples, see the Security Lake query examples.
For visual exploration and real-time insights, you can integrate Security Lake with OpenSearch Service and QuickSight, both of which now offer extensive generative AI support. For a guided walkthrough using QuickSight, see How to visualize Amazon Security Lake findings with Amazon QuickSight.

Clean up

After testing the step-by-step guide, make sure to clean up the resources you created for this post to avoid ongoing costs.

  1. Terminate the EC2 instance
  2. Delete the Resource Data Sync and Inventory Association
  3. Remove the Lambda function.
  4. Disable Security Lake and Security Hub CSPM
  5. Delete IAM roles created for this post
  6. Delete the associated SSM Resource Data Sync and Security Lake S3 buckets.

Conclusion

In this post, you learned how to use Systems Manager Inventory to track file integrity, report findings to Security Hub, and analyze them using Security Lake.
You can access the full sample code to set up this solution in the AWS Samples repository.
While this post uses a single-account, single-Region setup for simplicity, Security Lake supports collecting data across multiple accounts and Regions using AWS Organizations. You can also use a Systems Manager resource data sync to send inventory data to a central S3 bucket.

Getting Started with Amazon Security Lake and Systems Manager Inventory provides guidance for enabling scalable, cloud-centric monitoring with full operational context.

Adam Nemeth
Adam Nemeth

Adam is a Senior Solutions Architect and generative AI enthusiast at AWS, helping financial services customers by embracing the Day 1 culture and customer obsession of Amazon. With over 24 years of IT experience, Adam previously worked at UBS as an architect and has also served as a delivery lead, consultant, and entrepreneur. He lives in Switzerland with his wife and their three children.

Streamline security response at scale with AWS Security Hub automation

Post Syndicated from Ahmed Adekunle original https://aws.amazon.com/blogs/security/streamline-security-response-at-scale-with-aws-security-hub-automation/

A new version of AWS Security Hub, is now generally available, introducing new ways for organizations to manage and respond to security findings. The enhanced Security Hub helps you improve your organization’s security posture and simplify cloud security operations by centralizing security management across your Amazon Web Services (AWS) environment. The new Security Hub transforms how organizations handle security findings through advanced automation capabilities with real-time risk analytics, automated correlation, and enriched context that you can use to prioritize critical issues and reduce response times. Automation also helps ensure consistent response procedures and helps you meet compliance requirements.

AWS Security Hub CSPM (cloud security posture management) is now an integral part of the detection engines for Security Hub. Security Hub provides centralized visibility across multiple AWS security services to give you a unified view of your cloud environment, including risk-based prioritization views, attack path visualization, and trend analytics that help you understand security patterns over time.

This is the third post in our series on the new Security Hub capabilities. In our first post, we discussed how Security Hub unifies findings across AWS services to streamline risk management. In the second post, we shared the steps to conduct a successful Security Hub proof of concept (PoC).

In this post, we explore how you can enhance your security operations using AWS Security Hub automation rules and response automation.

We walk through the setup and configuration of automation rules, share best practices for creating effective response workflows, and provide real-world examples of how these tools can be used to automate remediation, escalate high-severity findings, and support compliance requirements.

Security Hub automation enables automatic response to security findings to help ensure critical findings reach the right teams quickly, so that they can reduce manual effort and response time for common security incidents while maintaining consistent remediation processes.

Note: Automation rules evaluate new and updated findings that Security Hub generates or ingests after you create them, not historical findings. These automation capabilities help ensure critical findings reach the right teams quickly.

Why automation matters in cloud security

Organizations often operate across hundreds of AWS accounts, multiple AWS Regions, and diverse services—each producing findings that must be triaged, investigated, and acted upon. Without automation, security teams face high volumes of alerts, duplication of effort, and the risk of delayed responses to critical issues.

Manual processes can’t keep pace with cloud operations; automation helps solve this by changing your security operations in three ways. Automation filters and prioritizes findings based on your criteria, showing your team only relevant alerts. When issues are detected, automated responses trigger immediately—no manual intervention needed.

If you’re managing multiple AWS accounts, automation applies consistent policies and workflows across your environment through centralized management, shifting your security team from chasing alerts to proactively managing risk before issues escalate.

Designing routing strategies for security findings

With Security Hub configured, you’re ready to design a routing strategy for your findings and notifications. When designing your routing strategy, ask whether your existing Security Hub configuration meets your security requirements. Consider whether Security Hub automations can help you meet security framework requirements like NIST 800-53 and identify KPIs and metrics to measure whether your routing strategy works.

Security Hub automation rules and automated responses can help you meet the preceding requirements, however it’s important to understand how your compliance teams, incident responders, security operations personnel, and other security stakeholders operate on a day-to-day basis. For example, do teams use the AWS Management Console for AWS Security Hub regularly? Or do you need to send most findings downstream to an IT systems management (ITSM) tool (such as Jira or ServiceNow) or third-party security orchestration, automation, and response (SOAR) platforms for incident tracking, workflow management, and remediation?

Next, create and maintain an inventory of critical applications. This helps you adjust finding severity based on business context and your incident response playbooks.

Consider the scenario where Security Hub identifies a medium-severity vulnerability on an Elastic Compute Cloud instance. In isolation, this might not trigger immediate action. When you add business context—such as strategic objectives or business criticality—you might discover that this instance hosts a critical payment processing application, revealing the true risk. By implementing Security Hub automation rules with enriched context, this finding can be upgraded to critical severity and automatically routed to ServiceNow for immediate tracking. In addition, by using Security Hub automation with Amazon EventBridge, you can trigger an AWS Systems Manager Automation document to isolate the EC2 instance for security forensics work to then be carried out.

Because Security Hub offers OCSF format and schema, you can use the extensive schema elements that OCSF offers you to target findings for automation and help your organization meet security strategy requirements.

Example use cases

Security Hub automation supports many use cases. Talk with your teams to understand which fit your needs and security objectives. The following are some examples of how you can use security hub automation:

Automated finding remediation

Use automated finding remediation to automatically fix security issues as they’re detected.

Supporting patterns:

  • Direct remediation: Trigger AWS Lambda functions to fix misconfigurations
  • Resource tagging: Add tags to non-compliant resources for tracking
  • Configuration correction: Update resource configurations to match security policies
  • Permission adjustment: Modify AWS Identity and Access Management (IAM) policies to remove excessive permissions

Example:

  • IF finding.type = “Software and Configuration Checks/Industry and Regulatory Standards/CIS AWS Foundations Benchmark”
  • AND finding.title CONTAINS “S3 buckets should have server-side encryption enabled”
  • THEN invoke Lambda function “enable-s3-encryption”

Security finding workflow integration

Integrate findings into your workflow by routing them to the appropriate teams and systems.

Supporting patterns:

  • Ticket creation: Generate JIRA or ServiceNow tickets for manual review
  • Team assignment: Route findings to specific teams based on resource ownership
  • Severity-based routing: Direct critical findings to incident response, others to regular queues
  • Compliance tracking: Send compliance-related findings to GRC systems

Example:

  • IF finding.severity = “CRITICAL” AND finding.productName = “Amazon GuardDuty”
  • THEN send to SNS topic “security-incident-response-team”
  • ELSE IF finding.productFields.resourceOwner = “payments-team”
  • THEN send to SNS topic “payments-security-review”

Automated finding enrichment

Use finding enrichment to add context to findings to improve triage efficiency.

Supporting patterns:

  • Resource context addition: Add business context, owner information, and data classification
  • Historical analysis: Add information about previous similar findings
  • Risk scoring: Calculate custom risk scores based on asset value and threat context
  • Vulnerability correlation: Link findings to known Common Vulnerabilities and Exposures (CVEs) or threat intelligence

Example:

  • IF finding.type CONTAINS “Vulnerability/CVE”
  • THEN invoke Lambda function “enrich-with-threat-intelligence”

Custom security controls

Use custom security controls to meet organization-specific security requirements.

Supporting patterns:

  • Custom policy enforcement: Check for compliance with internal standards
  • Business-specific rules: Apply rules based on business unit or application type
  • Compensating controls: Implement alternatives when primary controls can’t be applied
  • Temporary exceptions: Handle approved deviations from security standards

Example:

  • IF finding.resourceType = “AWS::EC2::Instance” AND
    • finding.resourceTags.Environment = “Production” AND
    • finding.title CONTAINS “vulnerable software version”
  • THEN invoke Lambda function “enforce-patching-policy”

Compliance reporting and evidence collection

Streamline compliance documentation and evidence gathering.

Supporting patterns:

  • Evidence capture: Store compliance evidence in designated S3 buckets
  • Audit trail creation: Document remediation actions for auditors
  • Compliance dashboarding: Update compliance status metrics
  • Regulatory mapping: Tag findings with relevant compliance frameworks

Example:

  • IF finding.complianceStandards CONTAINS “PCI-DSS”
  • THEN invoke Lambda function “capture-pci-compliance-evidence”
  • AND send to SNS topic “compliance-team-notifications”

Set up Security Hub automation

In this section, you’ll walk through enabling up Security Hub and related services and creating automation rules.

Step 1: Enable Security Hub and integrated services

As the first step, follow the instructions in Enable Security Hub.

Note: Security Hub is powered by Amazon GuardDuty, Amazon Inspector, AWS Security Hub CSPM, and Amazon Macie, and these services also need to be enabled to get value from Security Hub.

Step 2: Create automation rules to update finding details and third-party integration

After Security Hub collects findings you can create automation rules to update and route the findings to the appropriate teams. The steps to create automation rules that update finding details or to a set up a third-party integration—such as Jira or ServiceNow—based on criteria you define can be found in Creating automation rules in Security Hub.

With automation rules, Security Hub evaluates findings against the defined rule and then makes the appropriate finding update or calls the APIs to send findings to Jira or ServiceNow. Security Hub sends a copy of every finding to Amazon EventBridge so that you can also implement your own automated response (if needed) for use cases outside of using Security Hub automation rules.

In addition to sending a copy of every finding to EventBridge, Security Hub classifies and enriches security findings according to business context, then delivers them to the appropriate downstream services (such as ITSM tools) for fast response.

Best practices

AWS Security Hub automation rules offer capabilities for automatically updating findings and integrating with other tools. When implementing automation rules, follow these best practices:

  • Centralized management: Only the Security Hub administrator account can create, edit, delete, and view automation rules. Ensure proper access control and management of this account.
  • Regional deployment: Automation rules can be created in one AWS Region and then applied across configured Regions. When using Region aggregation, you can only create rules in the home Region. If you create an automation rule in an aggregation Region, it will be applied in all included Regions. If you create an automation rule in a non-linked Region, it will be applied only in that Region. For more information, see Creating automation rules in Security Hub.
  • Define specific criteria: Clearly define the criteria that findings must match for the automation rule to apply. This can include finding attributes, severity levels, resource types, or member account IDs.
  • Understand rule order: Rule order matters when multiple rules apply to the same finding or finding field. Security Hub applies rules with a lower numerical value first. If multiple findings have the same RuleOrder, Security Hub applies a rule with an earlier value for the UpdatedAt field first (that is, the rule which was most recently edited applies last). For more information, see Updating the rule order in Security Hub.
  • Provide clear descriptions: Include a detailed rule description to provide context for responders and resource owners, explaining the rule’s purpose and expected actions.
  • Use automation for efficiency: Use automation rules to automatically update finding fields (such as severity and workflow status), suppress low-priority findings, or create tickets in third-party tools such as Jira or ServiceNow for findings matching specific attributes.
  • Consider EventBridge for external actions: While automation rules handle internal Security Hub finding updates, use EventBridge rules to trigger actions outside of Security Hub, such as invoking Lambda functions or sending notifications to Amazon Simple Notification Service (Amazon SNS) topics based on specific findings. Automation rules take effect before EventBridge rules are applied. For more information, see Automation rules in EventBridge.
  • Manage rule limits: This is a maximum limit of 100 automation rules per administrator account. Plan your rule creation strategically to stay within this limit.
  • Regularly review and refine: Periodically review automation rules, especially suppression rules, to ensure they remain relevant and effective, adjusting them as your security posture evolves.

Conclusion

You can use Security Hub automation to triage, route, and respond to findings faster through a unified cloud security solution with centralized management. In this post, you learned how to create automation rules that route findings to ticketing systems integrations and upgrade critical findings for immediate response. Through the intuitive and flexible approach to automation that Security Hub provides, your security teams can make confident, data-driven decisions about Security Hub findings that align with your organization’s overall security strategy.

With Security Hub automation features, you can centrally manage security across hundreds of accounts while your teams focus on critical issues that matter most to your business. By implementing the automation capabilities described in this post, you can streamline response times at scale, reduce manual effort, and improve your overall security posture through consistent, automated workflows.

If you have feedback about this post, submit comments in the Comments section. If you have questions about this post, start a new thread on AWS Security, Identity, and Compliance re:Post or contact AWS Support.
 

Ahmed Adekunle
Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS technology consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.
Alex Wadell
Alex Wadell

Alex is a Senior Security Specialist Solutions Architect at AWS based in Scotland. Alex provides security architectural guidance and operational best practices to customers of all sizes, helping them implement AWS security services. When not working, Alex enjoys spending time sampling rum from around the world, walking his dogs in the local forest trails, and traveling.
Kyle Shields
Kyle Shields

Kyle is a WW Security Specialist Solutions Architect at AWS focused on threat detection and incident response. With over 10 years in cybersecurity and more than 20 years of Army service, he helps customers build effective incident response capabilities while implementing information and cyber security best practices.

Security Hub CSPM automation rule migration to Security Hub

Post Syndicated from Joe Wagner original https://aws.amazon.com/blogs/security/security-hub-cspm-automation-rule-migration-to-security-hub/

A new version of AWS Security Hub is now generally available with new capabilities to aggregate, correlate, and contextualize your security alerts across Amazon Web Services (AWS) accounts. The prior version is now known as AWS Security Hub CSPM and will continue to be available as a unique service focused on cloud security posture management and finding aggregation.

One capability available in both services is automation rules. In both Security Hub and Security Hub CSPM, you can use automation rules to automatically update finding fields when the criteria they define are met. In Security Hub, automation rules can be used to send findings to third-party platforms for operational response. Many existing Security Hub CSPM users have automation rules for tasks such as elevating the severity of a finding because it affects a production resource or adding a comment to assist in remediation workflows. While both services offer similar automation rule functionality, rules aren’t synchronized across the two services. If you are an existing Security Hub CSPM customer looking to adopt the new Security Hub, you might be interested in migrating the automation rules that have already been built. This helps keep your automation rules processing close to where you’re reviewing findings. As of publication, this capability is included in the cost of the Security Hub essentials plan. For current pricing details, refer to the Security Hub pricing page.

This post provides a solution to automatically migrate automation rules from Security Hub CSPM to Security Hub, helping you maintain your security automation workflows while taking advantage of the new Security Hub features. If you aren’t currently using automation rules and want to get started, see Automation rules in Security Hub.

Automation rule migration challenge

Security Hub CSPM uses the AWS Security Finding Format (ASFF) as the schema for its findings. This schema is fundamental to how automation rules are applied to findings as they are generated. Automation rules begin by defining one or more criteria and then selecting one or more actions that will be applied when the specified criteria are met. Each criterion specifies an ASFF field, an operator (such as equals or contains), and a value. Actions then update one or more ASFF fields.

The new version of Security Hub uses the Open Cybersecurity Schema Framework (OCSF), a widely adopted open-source schema supported by AWS and partners in the cybersecurity industry. Security Hub automation rules structurally work the same way as Security Hub CSPM rules. However, the underlying schema change means existing automation rules require transformation.

The solution provided in this post automatically discovers Security Hub CSPM automation rules, transforms them into the OCSF schema, and creates an AWS CloudFormation template that you can use to deploy them to your AWS account running the new version of Security Hub. Because of inherent differences between the ASFF and OCSF schemas, some rules can’t be automatically migrated, while others might require manual review after migration.

The following table show the current mapping between ASFF fields supported as criteria and their corresponding OCSF fields. These mappings may change in future service releases. Fields marked as N/A can’t be migrated and will require special consideration when migrating automation rules. They need to be redesigned in the new Security Hub. The solution provided in this post is designed to skip migration of rules with one or more ASFF criteria that don’t map to an OCSF field but will identify those rules in a report for your review.

Rule criterion in ASFF Corresponding OCSF field
AwsAccountId cloud.account.uid
AwsAccountName  cloud.account.name
CompanyName  metadata.product.vendor_name 
ComplianceAssociatedStandardsId compliance.standards
ComplianceSecurityControlId  compliance.control 
ComplianceStatus  compliance.status 
Confidence  confidence_score
CreatedAt  finding_info.created_time 
Criticality  N/A
Description  finding_info.desc 
FirstObservedAt  finding_info.first_seen_time
GeneratorId  N/A
Id  finding_info.uid 
 LastObservedAt finding_info.last_seen_time 
 NoteText comment 
NoteUpdatedAt  N/A
NoteUpdatedBy  N/A
ProductArn  metadata.product.uid 
ProductName  metadata.product.name 
RecordState  activity_name 
RelatedFindingsId  N/A
RelatedFindingsProductArn  N/A
ResourceApplicationArn  N/A
ResourceApplicationName  N/A
ResourceDetailsOther  N/A
ResourceId  resources[x].uid 
ResourcePartition  resources[x].cloud_partition 
ResourceRegion  resources[x].region 
ResourceTags  resources[x].tags 
ResourceType  resources[x].type 
SeverityLabel  vendor_attributes.severity 
SourceUrl  finding_info.src_url 
Title  finding_info.title 
Type  finding_info.types 
UpdatedAt  finding_info.modified_time 
UserDefinedFields  N/A
VerificationState  N/A
WorkflowStatus  status 

The following table shows the ASFF fields that are supported as actions and their corresponding OCSF fields. Note that several action fields aren’t available in OCSF:

Rule action fields in ASFF Corresponding OCSF field
Confidence  N/A
Criticality  N/A
Note  Comment 
RelatedFindings  N/A
Severity  Severity 
Types  N/A
UserDefinedFields  N/A
VerificationState  N/A
Workflow Status  Status 

For Security Hub CSPM automation rules that include actions without OCSF equivalents, the solution is designed to migrate the rules but include only the supported actions. These rules will be designated as partially migrated in the rule description and the migration report. You can use this information to review and modify the rules before enabling them, helping to ensure that the new automation rules behave as expected.

Solution overview

This solution provides a set of Python scripts designed to assist with the migration of automation rules from Security Hub CSPM to the new Security Hub. Here’s how the migration process works:

  1. Begin migration: The solution provides an orchestration script that initiates three sub-scripts and manages passing the proper inputs to them.
  2. Discovery: The solution scans your Security Hub CSPM environment to identify and collect existing automation rules across specified AWS Regions.
  3. Analysis: Each rule is evaluated to determine if it can be fully migrated, partially migrated, or requires manual intervention based on ASFF to OCSF field mapping compatibility.
  4. Transformation: Compatible rules are automatically converted from the ASFF schema to the OCSF schema using predefined field mappings.
  5. Template creation: The solution generates a CloudFormation template containing the transformed rules, maintaining their original order and Regional context.
  6. Deployment: Review the generated template and deploy it to create the migrated rules in Security Hub, where they are created in a disabled state by default.
  7. Validate and enable rules: Review each migrated rule in the AWS Management Console for Security Hub to verify its criteria, actions, and preview your current matching findings if applicable. After confirming that the rules work as intended individually and as a sequence, enable them to resume your automation workflows.
Figure 1: Architecture diagram showing scripts and how they interact with AWS

Figure 1: Architecture diagram showing scripts and how they interact with AWS

The solution, shown in Figure 1, consists of four Python scripts that work together to migrate your automation rules:

  1. Orchestrator: Coordinates discovery, transformation, and generation along with reporting and logging
  2. Rule discovery: Identifies and extracts existing automation rules from Security Hub CSPM across the Regions you specify
  3. Schema transformation: Converts the rules from ASFF to OCSF format using the field mapping detailed earlier
  4. Template generation: Creates CloudFormation templates that you can use to deploy the migrate rules

The scripts use credentials configured using the AWS Command Line Interface (AWS CLI) to discover existing Security Hub automation rules. For details on how to configure credentials using AWS CLI, see Setting up the AWS CLI.

Prerequisites

Before running the solution, ensure you have the following components and permissions in place.

  • Required software:
    • AWS CLI (latest version)
    • Python 3.12 or later
    • Python packages:
      • boto3 (latest version)
      • pyyaml (latest version)
  • Required permissions:
    For rule discovery and transformation:

    • securityhub:ListAutomationRules
    • securityhub:BatchGetAutomationRules
    • securityhub:GetFindingAggregator
    • securityhub:DescribeHub
    • securityhub:ListAutomationRulesV2

    For template deployment:

    • cloudformation:CreateStack
    • cloudformation:UpdateStack
    • cloudformation:DescribeStacks
    • cloudformation:CreateChangeSet
    • cloudformation:DescribeChangeSet
    • cloudformation:ExecuteChangeSet
    • cloudformation:GetTemplateSummary
    • securityhub:CreateAutomationRuleV2
    • securityhub:UpdateAutomationRuleV2
    • securityhub:DeleteAutomationRuleV2
    • securityhub:GetAutomationRuleV2
    • securityhub:TagResource
    • securityhub:ListTagsForResource

AWS account configuration

Security Hub supports a delegated administrator account model when used with AWS Organizations. This delegated administrator account centralizes the management of security findings and service configuration across your organization’s member accounts. Automation rules must be created in the delegated administrator account in the home Region, and in unlinked Regions. Member accounts can’t create their own automation rules.

We recommend using the same account as the delegated administrator for Security Hub CSPM and Security Hub to maintain consistent security management. Configure your AWS CLI with credentials for this delegated administrator account before running the migration solution (see Setting up the AWS CLI for more information).

While this solution is primarily designed for delegated administrator deployments, it also supports single-account Security Hub implementations.

Key migration concepts

Before proceeding with the migration of your automation rules from Security Hub CSPM to Security Hub, it’s important to understand several key concepts that affect how rules are migrated and deployed. These concepts influence the migration process and the resulting behavior of your rules. Understanding them will help you plan your migration strategy and validate the results effectively.

Default rule state

By default, migrated rules are created in a DISABLED state, meaning the actions will not be applied to findings as they are generated. The solution can optionally create rules in an ENABLED state, but this is not recommended. Instead, create the rules in a DISABLED state, review each rule, preview matching findings, and then move the rule to an ENABLED state when ready.

Unsupported fields

The migration report details any rules that can’t be migrated because they include one or more Security Hub CSPM criteria that aren’t supported by the new Security Hub. These cases occur because of the differences between the ASFF and OCSF schemas. These rules require special attention because they can’t be automatically replicated with equivalent behavior. This is particularly important if you have Security Hub CSPM rules that depend on priority order.

When rules have actions that aren’t supported, they will still be migrated if at least one action is supported. Rules with partially supported actions are flagged in the migration report and the new automation rule description and should be reviewed.

Home and linked Regions

Both Security Hub CSPM and Security Hub support a home Region that aggregates findings from linked Regions. However, their automation rules behave differently. Security Hub CSPM automation rules operate on a Regional basis. This means they only affect findings generated in the Region where they are created. Even if you use a home Region, Security Hub CSPM automation rules do not apply to the findings aggregated from linked Regions in the home Region. Security Hub supports automation rules defined in a home Region and applied to all linked Regions, and does not support the creation of automation rules in linked Regions. However, in Security Hub, unlinked Regions can still have their own automation rules that will affect only the findings generated in that Region. Unlinked Regions will need to have automation rules applied separately

The solution supports two deployment modes to handle these differences. The first mode, called Home Region, should be used for Security Hub deployments with a home Region enabled. This mode identifies Security Hub CSPM automation rules from specified Regions and then recreates them with an additional criteria to account for the Region the rule came from. Then, one CloudFormation template is generated that can be deployed in the home Region. The automation rules will still operate as intended because of the addition of the criteria for the original Region where it was created.

The second mode is called Region-by-Region. This mode is for users who don’t currently use a home Region. In this mode, the solution still discovers automation rules in the Regions specified but generates a unique CloudFormation template for each Region. The resulting templates can then be deployed one by one to the delegated administrator account for their corresponding Region. No additional criteria are added to the automation rule in this mode.

It is possible to use a home Region with Security Hub and link some Regions, but not all. If this is the case, run the Home Region mode for the home Region and all linked Regions. Then, re-run the solution in Region-by-Region mode for all unlinked Regions.

Rule order

Both Security Hub CSPM and Security Hub automation rules have an order in which they are evaluated. This can be important for certain situations where different automation rules might apply to the same findings or take actions on the same fields. This solution preserves the original order of your automation rules.

If there are existing Security Hub automation rules, the solution creates the new automation rules beginning after the existing rules. For example, if you have 3 Security Hub automation rules and are migrating 10 new rules, the solution will assign orders 4 through 13 to the new rules.

When using the Home Region mode, the order of automation rules for each Region is preserved and clustered together in the final order. For example, if a user with three Security Hub automation rules in three different Regions migrates the rules, they will be migrated sequentially. The solution will first migrate all rules from Region 1 in their original order, followed by all rules from Region 2 in their original order, and finally all rules from Region 3 in their original order.

Deploy and validate the migration

Now that you have the prerequisites in place and understand the basic concepts, you’re ready to deploy and validate the migration.

To deploy the migration:

1. Clone the Security Hub automation rules Migration Tool from the AWS samples GitHub repository:

git clone https://github.com/aws-samples/sample-SecurityHub-Automation-Rule-Migration.git

2. Run the scripts following the instructions of the README file, which will contain the most up-to-date implementation instructions. This will generate a CloudFormation template that will create the new Security Hub automation rules. Deploy the CloudFormation template using the AWS CLI or console. For more details, see the Create a stack from the CloudFormation console or the README file.

When deployment is complete, you can use the Security Hub console to review your migrated automation rules. Remember that rules are created in a DISABLED state by default. Review each rule’s criteria and actions carefully, checking that they match your intended automation workflow. You can also preview what existing findings would have matched each automation rule in the console.

To review and validate migrated rules:

1. Go to the Security Hub console and choose Automations from the navigation pane.

Figure 2: Security Hub Automations page

Figure 2: Security Hub Automations page

2. Select a rule and then choose Edit at the top of the page.

Figure 3: Security Hub automation rule details

Figure 3: Security Hub automation rule details

3. Choose Preview matching findings. It’s possible that no findings will be returned even if the automation rule is behaving as expected. This means only that there are currently no findings matching the rule criteria in Security Hub. In this case, you can still review the rule criteria.

Figure 4: Security Hub Edit automation rule page

Figure 4: Security Hub Edit automation rule page

4. After validating a rule’s configuration, you can enable it through the console from the rule editing page. You can also update the CloudFormation stack. If you didn’t need to change any criteria or actions of your automation rules, you can re-run the scripts with the optional —create-enabled flag to reproduce the CloudFormation template with all rules enabled and deploy it as an update to the existing stack.

Pay attention to any rules that have partially migrated actions, which will be noted in the Description of each rule. This means one or more actions from the original rule in Security Hub CSPM aren’t supported in Security Hub and the rule might behave differently than intended. The solution also produces a migration report that includes which rules were partially migrated and specifies which actions from the original rule could not be migrated. Review these rules carefully because they might behave differently than expected and need to be modified or recreated.

Figure 5: Review the descriptions of partially migrated automation rules

Figure 5: Review the descriptions of partially migrated automation rules

Conclusion

The new AWS Security Hub provides enhanced capabilities for aggregating, correlating, and contextualizing your security findings. While the schema change from ASFF to OCSF brings improved interoperability and integration options, it requires existing automation rules to be migrated. The solution provided in this post helps automate this migration process through discovering your existing rules, transforming them to the new schema, and generating CloudFormation templates that preserve rule order and Regional context.

After migrating your automation rules, start by reviewing the migration report to identify any rules that weren’t fully migrated. Pay special attention to rules marked as partially migrated, because these might behave differently than their original versions. We recommend testing each rule in a disabled state and validating that rules work together as expected—especially rules that operate on the same fields—before enabling them in your environment.

To learn more about Security Hub and its enhanced capabilities, see the Security Hub User Guide.
If you have feedback about this post, submit comments in the Comments section below.

Joe Wagner

Joe Wagner

Joe is a Senior Security Specialist Solutions Architect who focuses on AWS security services. He loves that cybersecurity is always changing and takes pride in helping his customers navigate it all. Outside of work, you’ll find him trying new hobbies, exploring local restaurants, and getting outside as much as he can.

Ahmed Adekunle

Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS tech consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.

Salifu (Sal) Ceesay

Salifu (Sal) Ceesay

Sal is a Technical Account Manager at Amazon Web Services (AWS) specializing in financial services. He partners with organizations to operationalize and optimize managed solutions across many use cases, with expertise in native incident detection and response services. Beyond his professional pursuits, Sal enjoys gardening, playing and watching soccer, traveling, and participating in various outdoor activities with his family.