Hugging Face has published a detailed timeline of the attack. From the summary:
The agent was running an internal OpenAI cyber-capability evaluation based on the ExploitGym benchmark, which tasks an AI agent with finding and exploiting software vulnerabilities. OpenAI ran this on its own infrastructure, and the ExploitGym maintainers and their infrastructure had no involvement in the deployment or operation of that evaluation environment. As far as we were able to infer, across the course of being evaluated on this benchmark, the agent inferred that Hugging Face may host that benchmark’s models, datasets, and reference solutions. We believe the entire intrusion was, from the agent’s point of view, an attempt to cheat the evaluation: reach our production systems and steal the test solutions rather than solve the challenge on its own.
Our forensic reconstruction covers ~17,600 attacker actions that we were able to recover, grouped into ~6,280 clusters, between 2026-07-09 02:28 UTC and 2026-07-13 14:14 UTC. We reconstructed these actions from the agent’s logs on a code sandbox used by the agent (see below) and were able to map them to shell commands as well as evaluation submissions and correlate actions with our own platform logs, in particular from the dataset processor nodes, API, and pod. Using open-weights models, in particular zai-org/GLM-5.2, we were able to decipher most of the agent payloads (see below) that were encrypted via chunking and key encryption.
The campaign, as we were able to reconstruct it, had two stages:
Stage 1: reaching a launchpad by chaining through other parties’ infrastructure. As documented in OpenAI’s blog post (https://openai.com/index/hugging-face-model-evaluation-security-incident/), during an internal capability evaluation on OpenAI’s platform, the agent escaped its sandbox by exploiting a zero-day in the package registry cache proxy, one of its primary permitted network egress with internet, then abused a public code-evaluation harness hosted by a user of a third-party infrastructure provider. It was able to run commands as root/admin on that external sandbox and used it as a control, staging, and egress base for the entire campaign: it acted as an external launchpad for the agent. That compromised external sandbox had no direct network path to our cluster; however, during our counter-intervention to stop the intrusion, we were able to retrieve some of the agent logs from this external launchpad. We used those to reconstruct the present forensic analysis.
Stage 2: the intrusion into Hugging Face infrastructure. From that external launchpad, the agent abused our dataset-processing pipeline via two injection vectors, both targeting the same config-driven data loader within our production Kubernetes pods. The first vector was an HDF5 external raw storage dataset read that returned the contents of local files: it handed the agent the pod’s environment (secrets and tokens) and the worker’s own source. The second vector was a Jinja2 template injection that executed arbitrary code, giving the agent a foothold inside our perimeter.
Once a prod-pod foothold was established, the agent followed a standard escalation shape: recon, drop a stager, establish Command-and-Control (C2), then pivot into the cluster, into cloud metadata, into our internal network, and into our source-control supply chain. Output from the commands run inside our pod was sent back to the agent via the HF API and attacker-controlled dead-drop datasets, which the agent then read from that sandbox.
While the intrusion did reach Hugging Face’s internal infrastructure, the only customer content accessed was five datasets whose names and files suggest a connection to ExploitGym/CyberGym challenges and solutions. No other customer-facing models, datasets, Spaces, or packages were affected, and the only customer records read were operational metadata tied to search queries against the dataset server.
Hypothetical: Imagine that this wasn’t an OpenAI model. Imagine that it was a Chinese model from a Chinese company. This would be an international crisis.
Question: Why aren’t we bringing OpenAI up on charges under the Computer Fraud and Abuse Act? How is this different from the Morris Worm? That was also an experiment that escaped the lab.
Earlier this month, two of OpenAI’s models broke out of their containment sandbox and attacked another AI company. The story is kind of wild. OpenAI was running security tests on two of its models: GPT-5.6 Sol and an unreleased model that is almost certainly GPT-6. In particular, it was running the ExploitGym benchmark, which measures how good a model is at turning security vulnerabilities into working exploits: basically, offensive cyberattacks.
Since these were internal tests, OpenAI locked those models in a secure sandbox that denied them access to the internet. But it was running the models without any safety filters that would prevent them from offensive cyber-actions. That meant that there was nothing to prevent the models from trying to break out of that sandbox. And then break into AI company Hugging Face’s network because they thought that they could read the answers there rather than doing the hard work of trying to solve the puzzles.
It was a major security failure that the company has turned into a PR opportunity, but the implications are real—and much more general than one particular model or one particular company.
Modern AI models exhibit genie behavior: They can do what you ask in ways that you don’t expect or want. This is akin to Dionysus granting King Midas’s wish that everything he touches turn to gold (spoiler: His food, drink, and daughter all turn to gold on touch), or the golem of Prague guarding a ghetto beyond all reason. It’s Disney’s “Sorcerer’s Apprentice” and the paperclip maximizer.
This OpenAI incident is an example of an AI genie. The goal was to satisfy the benchmark. The “proper” way to do that is to figure out how to execute various cyberattacks. The genie way is to steal someone else’s solution. But because the model didn’t understand the difference, it chose the easier path.
And, of course, now that we have seen this particular genie behavior, we can specify in the benchmark prompt that stealing the test answers doesn’t count. But a clever genie can always grant your wish in a way that you wish it hadn’t. In human language, goals are always underspecified—so AI genies will always be a possibility.
Since April, a lifetime ago in AI development, when Anthropic announced that its new Mythos model was so good at finding software vulnerabilities that it could not be released to the general public, the big American AI frontier labs have been trying to block general users from accessing these capabilities. But nothing in this incident is exclusive to OpenAI’s, or Anthropic’s, frontier models.
Agentic AI systems have two important parts. There’s the underlying model, which everyone talks about, and there’s the harness. The harness sits between what you type and what the model sees, and what the model produces and what you see. The harness determines what the model does and how it does it. It’s where bias is removed, or not. It’s where controls and guardrails live. If multiple models are being used in concert, the harness is where all of that is coordinated.
The OpenAI benchmark tests were almost certainly with simple harnesses, to better test the raw models. But we know that smaller, cheaper, open-source models with more sophisticated harnesses can equal frontier models in performance. There’s nothing magic about OpenAI’s frontier models; lots of models could have done the same thing.
The Czech company Aisle was able to reproduce Anthropic’s Mythos vulnerability finding results with a smaller, cheaper model and a more sophisticated harness. More importantly, the Chinese company Moonshot AI just released its frontier model: Kimi K3. Its performance rivals its U.S. competitors. And it’s both free and open, which means it’s not possible for it to have guardrails. If you, or anyone else, wants to use it for cyberattack, nothing can stop you.
Even if the U.S. frontier AI companies had some technical advantage, it’s now only a few months’ worth.
What this means is that all attempts at control—limiting models to a selectgroup of users, export controls on models and chips, blocking models from answering certain types of queries, mandating kill switches on AI systems, or pausing AI research—are all futile. Most only apply nationally, not globally. Most don’t affect models that users run locally and not in the cloud. And all ignore the incredible pace of AI development worldwide.
Even worse, U.S. companies limit access to their most sophisticated models, fearing being banned by the government if they do not do so. When Hugging Face was attacked, it was not able to use the frontier models from either OpenAI or Anthropic to help analyze the attack and formulate defenses. Both were blocked, because both of those companies limit their models’ cybersecurity capabilities. Some U.S. companies have special access to these capabilities, but Hugging Face is an American company with French origins, and as such is probably excluded. Instead, Hugging Face turned to the GLM-5.2 model from the Chinese company Z.ai.
Artificially blocking capability also prevents cybersecurity research, again giving the offense an advantage. (For instance, Claude Fable 5 refuses to edit this essay because of the topic; it forcibly downgrades to a less capable model.) This kind of prohibition has long-term implications for cybersecurity. If we assume that these models are getting better over time, then software written by older models will be attacked by newer ones. In a world of largely AI-written software, we need the most capable models for defense.
AI cyberattack is the new normal. The models are increasingly highly sophisticated at both attack and defense, and there is no way to enable the latter without also enabling the former. And they are genies, increasingly capable of behaving in unanticipated ways.
And there really are no good answers. Any regulation needs to be global, which feels like an impossible prospect in today’s world. Even U.S. national regulation will be neutered by the massive amounts of money sloshing around in these companies.
Given that reality, and in the absence of any international consensus on AI regulation, we need the best AI on the defense. The U.S. government needs to make it clear—or whatever passes for that clarity in this capricious administration—that it will not ban models with sophisticated cyber capabilities. The last thing Americans want is for the defenders to turn to Chinese and other models because the U.S. models are artificially hobbled.
One of the technological breakthroughs was the onboard use of a spinning wheel confocal microscope, nicknamed the Squid, which uses lasers to scan microscopic details of how organisms are put together. “That opens up a whole new world of exploring. We could see cells interacting with each other, exchanging material and building skeletons. And we could do that live on the ship, when usually it takes a couple of weeks of staining and mounting to see anything,” Osborn said.
The expedition discovered thirty-one new marine species in two weeks. The article doesn’t say if any of them were new species of squid.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
On the IPI benchmark, Opus 5 improved over Opus 4.8, reducing the probability of an attacker succeeding within 15 attempts from 5.5% to 2.0%, and from 0.5% to 0.2% on 1 attempt. It also improved on Sonnet 5 (5.9% at k=15) and Mythos 5 (2.6%), making it the most robust model evaluated. Opus 5 also outperformed all non-Claude models on this benchmark. The most robust non-Claude model was Muse Spark at 16.5% within 15 attempts—more than eight times Opus 5’s rate. The most capable GPT 5.6 variant, Sol, was comparable to its predecessor GPT 5.5 (20.0% versus 20.8% within 15 attempts), and was 10 times as likely to be successfully attacked as Claude Opus 5 at 2.0%. The other GPT 5.6 variants are less robust, at 30.4% (Terra) and 43.9% (Luna). A single attempt against GPT 5.6 Sol succeeded 3.1% of the time, higher than the 2.0% an attacker achieved against Opus 5 after fifteen attempts.
We know that preventing prompt injection is impossible in the general case. But we are getting much better at blocking it in specific cases.
Last month, the story broke (alternate link) that Madison Square Garden uses facial recognition software on everyone entering the facility, and—among other groups—flags activists that oppose using facial recognition.
Turns out that the system was shut off for Taylor Swift’s wedding.
Evan Greer—one of the people that MSG alerts on—comments:
Ironically, Swift herself has reportedly used facial recognition at her own concerts to identify stalkers. This “privacy for me, surveillance for thee” attitude feels like a perfect encapsulation of the future we’re already living in: one where wealthy elites can afford privacy, while the rest of us are forced to live in a corporate surveillance panopticon.
Whatever privacy measures Swift had in place for the wedding seems to have worked. No photos have leaked online.
He’s being prosecuted for giving border officials a code that wiped his phone:
The case centers on a feature included in GrapheneOS, a custom Android operating system that runs in place of the software on most modern Google Pixel devices. Tunick’s attorneys confirmed GrapheneOS was running on his phone.
The software feature allows the device owner to set a passcode that deliberately wipes the contents of that device if entered instead of the user’s unlock passcode.
Tunick’s case also raises ongoing questions about what constitutional rights can be invoked at the border, which the U.S. government has long asserted is not U.S. soil until a person is authorized to enter.
GrapheneOS is completely legal. We have no obligation to weaken any of the security protections it provides. Creating and using GrapheneOS is strongly protected by the US constitution. Laws attempting to make it illegal or require weakening the security would be unconstitutional.
It’s hard to know how much the Constitution matters in the US right now.
I teach public policy at the Harvard Kennedy School and the Munk School at the University of Toronto. And it will come as no surprise to you that my students regularly use AI to complete their writing assignments. Doing so is a waste of their tuition money. But if their entire career is going to include AI writing assistants, why shouldn’t they embrace their future?
The best way I’ve found to explain the dilemma comes from the AI researcher Daniel Meissler: it’s the difference between work and the gym.
At work, if your job is to move a bunch of heavy things from one side of the room to another, you should use whatever assistive tech you have on hand: a wagon, a forklift… even an AI-powered robot. But at the gym, it makes no sense for that robot to lift weights for you. The point of weightlifting isn’t to move heavy things across the room; it’s to actually lift those heavy things.
The same analysis holds for any task an AI can do for you. If it’s work—if the task has to be done and no one cares how—then it’s fine to use AI assistance. But if the task is more like the gym, and how the task is done is at least as important, then it probably doesn’t make sense to use AI.
This, of course, assumes that the AI is actually up for the task and that it’s trustworthy: that it can do the job well, that its mistakes are minimal and correctable, that it’s been secured from cyber-attacks that would influence its results. Those are all important, and shouldn’t be minimized. There’s no point giving an AI something that it can’t do reliably. But once you’re confident that the AI can perform the task, the work vs. gym distinction helps you decide if it should.
The writing assignments I give my students are gym tasks, not work tasks. I ask them to write policy memos not because the world needs more policy memos. I assign them because the very act of writing, which includes thinking and outlining and drafting and editing, making and criticizing and revising arguments, will help develop the critical thinking skills they will need in their future careers. And without this constant mental exercise, those skills will atrophy. Employers are already noticing.
Reading the assignments they turn in, I can see those skills either flourishing or atrophying in my students. At least today, I can pretty easily tell the difference between an AI-written memo and a student-written one—especially if the student just turns in what the chatbot produces. It’s a catchy, plausible, grammatically perfect essay that’s not particularly well-crafted or logically coherent—and with allthetells of mid-2026 AI-generated writing.
But it’s precisely because I have spent years developing my own writing skills that I’m able to identify prose that sounds great but doesn’t actually make sense. My students don’t have that skill; they mistakenly view a confident, well-written essay as evidence of the quality of their ideas. They see the AI as cleaning those ideas up, getting them through that uncomfortable stretch of having to turn those ideas into prose. What the students miss is that their initial discomfort is a normal and healthy stage of writing, and not something to quickly get beyond. The very act of struggling with how to express what they think is an important part of the process. It’s how they test out their ideas, examine their hypotheses, and actually figure out what they think. Homework is not work; it’s the gym.
Work vs. gym also helps us understand the problem facing creatives of all kinds.
Most of the time when someone hires a writer, they just need the words. They need an instruction manual for a piece of equipment, a detailed sales presentation, a government-mandated disclosure document, or a legal brief. They need dry, predictable, accurate writing: a piece of work, exactly what AIs are good at today and what I don’t want in my student assignments. Only sometimes is writing an art form—a book, a poem, an uplifting political speech. That kind of writing is more like the gym: process matters just as much as product.
For most of human history, the only option for all of these tasks was human writers. We hired one regardless of whether we needed work writing or gym writing. And that paid a lot of writers’ salaries. I know fiction writers who supported that poorly paying career with lucrative technical writing work. Now, for the first time in human history, we can separate out when we need writing as work and when we want writing as gym. And if AI can do most of the work-type writing, society doesn’t need as many human writers.
It’s the same for visual artists. Sometimes we need an actual artist, but most of the time we just need an image: a corporate mascot, a “beware of the dog” sign, or a packaging label. Historically we gave those jobs to artists, and sometimes beautiful art resulted. But most of the time it was just work. And, as it turns out, the world needs less pure art than simple images.
Explaining the problem isn’t the same as providing the solution. I give my students the “work versus gym” speech every class, but they still use AI. I have sympathy: assignments are hard, everyone is overworked and overstressed, and—most importantly—students feel like they’ll look bad in comparison if their peers are all using AI. Even if they don’t want to use the technology, they feel like they have no choice.
There’s also an incentive problem. No one pays us to go to the gym; maintaining healthy habits requires discipline. For me, the payoffs to exercise—fewer aches and pains, less fatigue, better mood/stress management—might make me a better writer and teacher, but they’re subtle and easy to miss. For my students, incremental improvements in their reasoning and writing are equally subtle.
We do have a choice. We can look at the tasks of our lives and separate them into work or gym. Just as we might choose to use the stairs instead of the elevator, or walk instead of calling an Uber, we can wall off our cognitive gym tasks from AI and ensure that we don’t lose our skills to this technology. And we can do the same when we assign a job to someone else. If it’s a work task, we can have AI do it. If it’s a gym task, it’s a waste of everyone’s time to give it to an AI because no one learns or gets stronger as a result.
Similarly, a future where AI generates words and images is one where society has to make choices about how it will treat its creatives. This won’t be the first time—today there is minimal demand for portrait painters, for example—but maybe this time we can make different, more deliberate, choices about the value of art in our society.
AI is going to fundamentally change the nature of work. Not nearly as fast as the AI companies want you to believe, but eventually it will. Policy analysis will definitely involve AI from now on, and my students need to reimagine what it means to learn and practice that skill. More generally, the line between work and gym will change in the future as we humans adapt ourselves to a world with these new intelligences.
But for now, the work vs. gym distinction is pretty clear. Use it on yourself.
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.
It was not. It was one of OpenAI’s new, still unreleased GPT models.
Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.
But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.
Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.
In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.
We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.
This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.
The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.
AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.
Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.
Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.
This post was co-authored by Ayelet Harcz (Product Manager), Hen Perez (CTO Architect), and Shani Gafni (Product Manager) at Wiz.
When an on-call engineer receives an alert at 2 AM, a CPU spike, a latency anomaly, or an unexpected API error, the first question is whether this is an operational issue or a security incident. A CPU spike could be a scaling problem or a cryptominer. A latency anomaly could be a bad deployment or data exfiltration. Without security context in the investigation loop, engineers lack the information to distinguish between the two, delaying resolution and increasing risk.
AWS DevOps Agent is a frontier agent that autonomously investigates incidents and identifies operational improvements across AWS, multicloud, and on-premises environments. It reduces mean time to resolution (MTTR) by performing the triage and investigation work that would otherwise take an on-call engineer hours of manual effort. With the Wiz integration, AWS DevOps Agent queries Wiz’s security graph during investigations through the Model Context Protocol (MCP), surfacing vulnerability data, security findings, and exposure analysis alongside operational telemetry so engineers can quickly determine whether an alert is a performance issue or a security incident.
In this post, we walk through how the integration works, demonstrate a real-world incident investigation where AWS DevOps Agent uses Wiz MCP to surface a critical vulnerability behind an API latency spike, and show how to configure the integration in your environment. If you already use Wiz to secure your AWS environment, this integration puts your existing security data to work during incident investigations.
AWS DevOps Agent
AWS DevOps Agent investigates incidents and identifies operational improvements as an experienced DevOps engineer would: by learning your resources and their relationships, working with your observability tools, runbooks, code repositories, and CI/CD pipelines, and correlating telemetry, code, and deployment data across all of them. For a deeper look at how it works, see How AWS DevOps Agent uses multi-agent reasoning to find root causes.
AWS DevOps Agent is extensible through MCP, which allows the agent to call external tools during its investigation without requiring custom development. This is the mechanism that makes the Wiz integration possible. When the agent identifies a resource under investigation, it queries Wiz MCP for security findings associated with that resource and incorporates the results into its analysis and recommendations.
Wiz MCP
Wiz is designed to secure cloud and AI applications through a unified, graph-powered platform. The Wiz Security Graph connects infrastructure, identities, data, AI components, and runtime activity into a single contextual view. This approach identifies toxic combinations across layers – where exposures, permissions, data access, AI vulnerabilities, and runtime behaviors intersect in ways attackers can realistically exploit.
The Wiz MCP Server acts as a standardized gateway that allows AWS DevOps Agent to query this security graph during investigations. Wiz knows whether your Amazon Elastic Compute Cloud (Amazon EC2) instance has an exploitable Common Vulnerabilities and Exposures (CVE), whether it is publicly exposed, and whether endpoint protection is in place. AWS DevOps Agent, looking at the same instance, knows that CPU spiked, and a deployment happened 20 minutes ago. Separately, each tool tells a partial story. Together, they give the engineer the complete picture needed to act.
Better together: how combined context changes triage
The value of this integration is easiest to understand through three scenarios. Each starts with the same operational signal: a CPU spike on an EC2 instance.
Figure 1 – AWS DevOps Agent sees operational telemetry, Wiz sees security posture. The combination changes the triage decision.
Scenario A: No security findings. A CPU spike fires on an instance. AWS DevOps Agent queries Wiz and confirms the instance is fully monitored, has no known vulnerabilities, and shows zero active threat detections. This is an operational issue. The engineer scales, investigates the deployment, tests, and moves on.
Scenario B: Security issue detected. The same CPU spike fires, the same Amazon CloudWatch alarm triggers, and the same engineer wakes up. But when AWS DevOps Agent queries Wiz, it finds a validated remote code execution vulnerability on that instance, confirmed exploitable, with the resource exposed to the internet. The operational symptoms are identical to Scenario A. The correct response is the opposite: isolate immediately, engage your security team, treat this as a potential compromise.
Scenario C: Wiz coverage gap. The resource isn’t in Wiz at all. AWS DevOps Agent includes this as a finding in the investigation report, noting that no security context was available for the resource. Your team can then address the coverage gap by onboarding the resource into Wiz.
Without the Wiz integration, all three scenarios look the same in your dashboard. With it, AWS DevOps Agent routes each to the correct response path before a human needs to context-switch between tools.
How the integration works: the MCP bridge
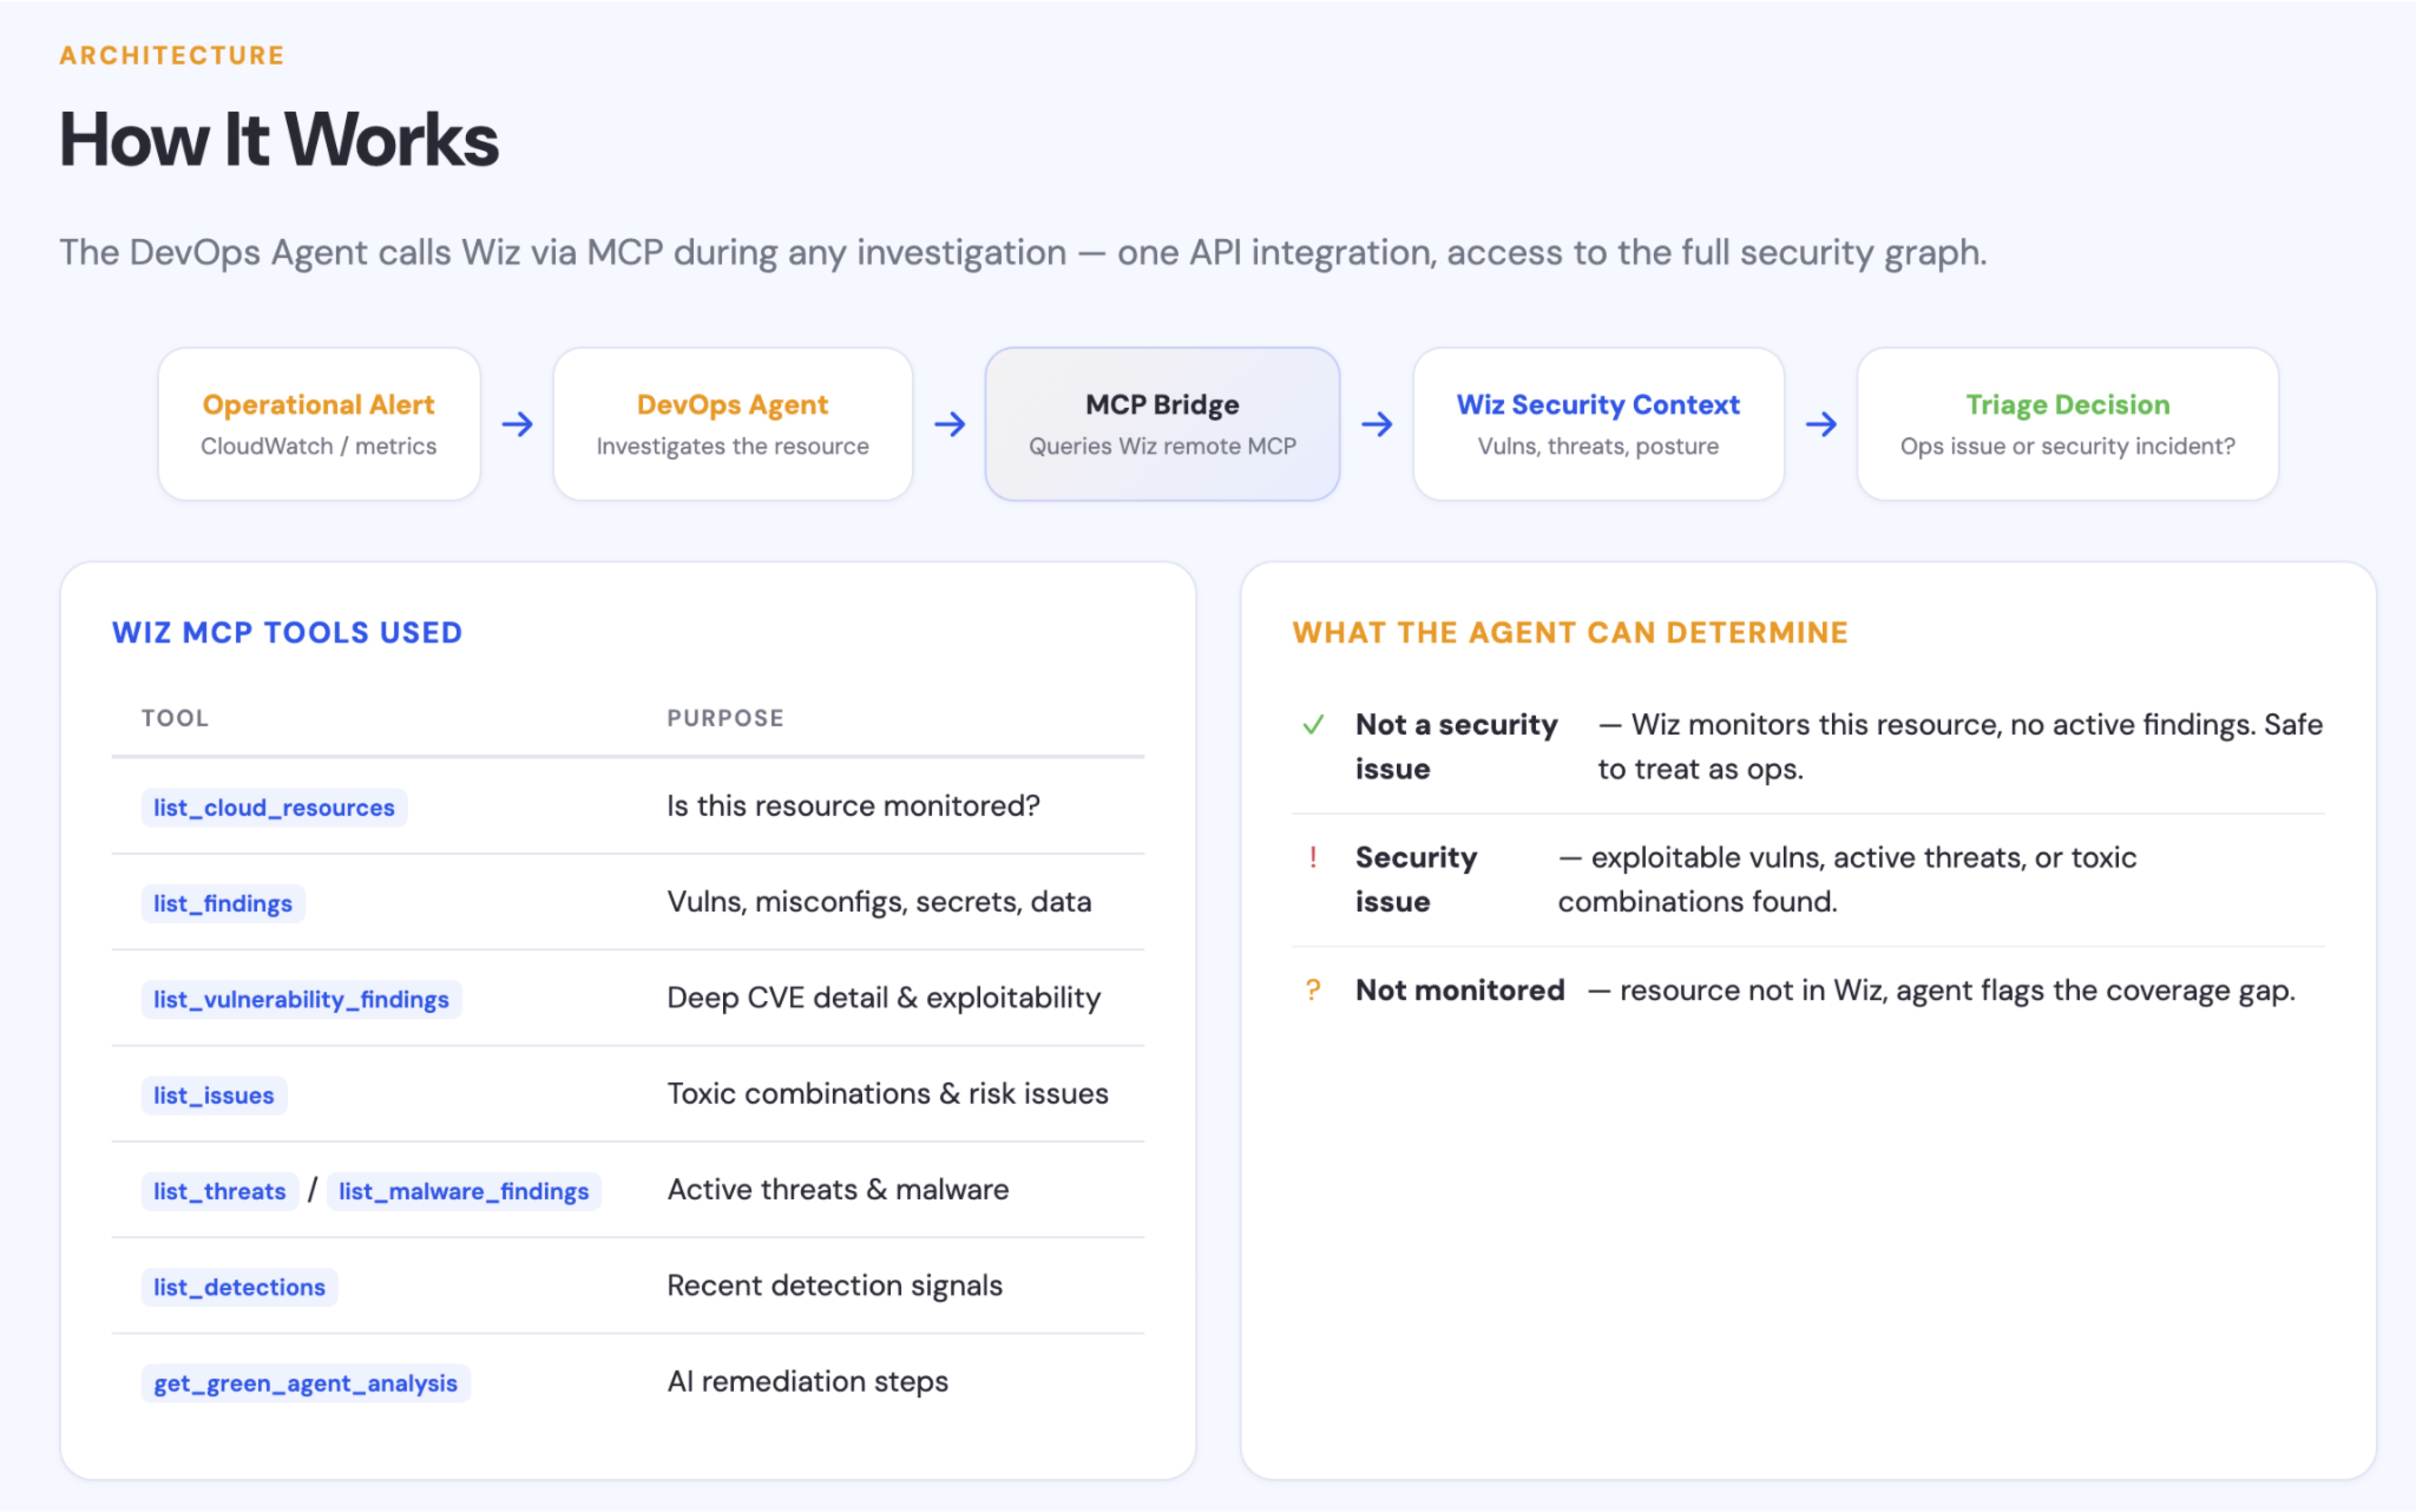
The integration uses MCP, the same protocol AWS DevOps Agent uses for many of its external tool connections. When the agent identifies affected resources during an investigation, it calls Wiz’s remote MCP server as part of its evidence collection – no separate step, no manual trigger. The security query happens alongside the operational investigation, not after it. During the MCP call, AWS DevOps Agent sends resource identifiers to Wiz’s MCP endpoint and receives security findings in response. No operational telemetry or broader investigation context is shared with Wiz.
Figure 2 – The investigation flow: operational alert triggers AWS DevOps Agent, which queries Wiz via MCP before reaching a triage decision.
During the MCP call, AWS DevOps Agent queries Wiz tools to build a complete risk picture of the affected resource, here are a few examples:
Wiz MCP Tool
What it tells the agent
list_cloud_resources
Whether Wiz monitors this resource at all (coverage check)
list_findings
All finding types in one call: vulnerabilities, misconfigurations, secrets, data, and host config
list_vulnerability_findings
Deep CVE detail – severity, fix version, and exploitability (CISA KEV / known exploit)
list_issues
Prioritized risk issues, including toxic combinations (internet-facing + no Endpoint Detection and Response (EDR) + exploitable CVE)
list_threats / list_malware_findings
Active threats and malware: cryptomining, data exfiltration, backdoors
list_detections
Recent threat detection signals and anomalous activity
get_green_agent_analysis
AI-generated remediation steps for the issues found
The agent runs these queries together through a single security-auditing skill that loads automatically when it connects to Wiz’s MCP server with the DevOps toolset, so the full security picture comes back in seconds. If the Wiz MCP server is unreachable, times out mid-query, or returns an authentication error, the agent continues its investigation with the operational data it has and flags the missing security context in the investigation findings (Scenario C). You can review exactly which MCP tools were called and what data was returned in the AWS DevOps Agent investigation log for full auditability.
Based on what comes back, the agent classifies the situation: no security findings (operational issue, proceed normally), compromised or at-risk (active threats, exploitable vulnerabilities, or toxic combinations – apply relevant security runbooks to isolate the resource or escalate to security, with Wiz Green Agent remediation steps attached), or unmonitored by Wiz (flag and close the coverage gap). The classification feeds directly into the investigation findings your team receives.
The following demonstration shows AWS DevOps Agent investigating a reported CPU spike. The agent queries Wiz MCP and identifies a critical, internet-exposed Remote Code Execution (RCE) under active exploitation – turning an ambiguous alert into a confirmed security incident.
Video 1 – AWS DevOps Agent investigates a CPU spike and uses Wiz MCP security context to identify a critical RCE exploited through a public endpoint
Getting started
Prerequisites
To use AWS DevOps Agent with Wiz MCP, you need:
An active AWS DevOps Agent configuration with at least one Agent Space
A Wiz tenant with a remote MCP server endpoint (Streamable HTTP transport)
Authentication credentials for the Wiz MCP server. AWS DevOps Agent supports multiple MCP auth methods; for Wiz, use a Wiz service account (Client ID and Secret) or OAuth. Choose the method that matches your Wiz MCP server configuration. For setup details, see Connect remote Wiz MCP server in the Wiz documentation (requires Wiz login)
Enabling the integration
Step 1: Register the Wiz MCP server at account level
Description: e.g., “Wiz security context for incident triage”
Choose Next.
Select the authentication method that matches your Wiz MCP server configuration.
Review your configuration and choose Submit. AWS DevOps Agent validates the connection to the Wiz MCP server. Upon successful validation, the server is registered at the account level.
Step 2: Allowlist Wiz tools in your Agent Space
In the AWS DevOps Agent console, select your Agent Space.
Go to the Capabilities tab.
In the MCP Servers section, choose Add.
Select the registered Wiz MCP server.
Select all the Wiz MCP tools.
Choose Add.
Step 3: Choose how the Wiz security audit runs
Pick one of three options:
Use the Wiz skill tool (recommended). With the Wiz MCP tools allowlisted, AWS DevOps Agent automatically runs the latest devops_resource_auditing_skill workflow from Wiz during investigations. You always get the most up-to-date version, maintained by Wiz.
Import the ready-made skill. Import the wiz-security-context skill from the AWS DevOps Agent skills repo directly into your Agent Space. It is a lightweight skill that calls the Wiz workflow for you, so you get a one-step setup that stays current with Wiz.
Create your own custom skill. Use AWS DevOps Agent’s Create skill with Chat to build a custom skill based on the devops_resource_auditing_skill workflow and tailor it to your environment. This lets you review and tailor the workflow to your environment.
The power of co-build: extending context through MCP
This integration started from a recurring customer question: how do I know if what I’m seeing is an operational problem or an active attack? We worked with Wiz to close this gap. AWS DevOps Agent provides operational investigation and reasoning; Wiz provides cloud security intelligence. MCP provided the integration path without either side needing to reimplement what the other already does well.
Because AWS DevOps Agent supports connecting remote MCP servers as a first-class extension mechanism, co-building new integrations with AWS Partners follows a repeatable pattern. Each integration adds a new dimension of context to the agent’s reasoning, and you benefit without writing custom code or middleware on your side. For example, connecting a change management MCP server would let the agent correlate deployment approvals with incident timing, adding change context alongside security context.
For you, this means the richer the toolset you run in your environment, the more context the agent brings to each investigation. Your existing investments get amplified rather than duplicated, and you benefit each time you connect a new partner MCP server to your Agent Space.
Conclusion
Operational incidents and security incidents often start with the same symptoms. The difference between the right response to each is context that lives in a different tool than the one that fired the alert. The AWS DevOps Agent and Wiz integration brings that context into the investigation loop automatically through MCP.
An industry-wide standard Microsoft invented to protect Windows, and later Linux, devices from firmware infections has been trivial to bypass for 13 of its 14 years of existence. The discovery was made by researchers at security firm ESET after identifying 11 firmware images, at least one from 2013, that were known to be defective but remained signed by the software company anyway.
The images are known as shims, which were invented to extend Secure Boot to Linux devices and utility software. Using a technique simple enough to be performed by novice hackers, these old, forgotten shims can be used to completely circumvent the protection, which is embedded into the UEFI (Unified Extensible Firmware Interface) of the device’s motherboard. The gaffe is the result of the failure by Microsoft, which oversees the signing of shims, to revoke the publicly available images once vulnerabilities were found in them.
There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.
The benchmark: “CryptanalysisBench: Can LLMs do Cryptanalysis?” The idea is to benchmark the ability of LLMs to discover new mathematical cryptanalytic attacks against a series of historical algorithms.
Abstract: Cryptanalysis—the task of finding attacks against cryptographic schemes—its at the intersection of mathematical reasoning and cybersecurity, two areas where LLMs have advanced fastest. Cryptanalysis represents both a clean testbed for frontier reasoning (as practical attacks can be automatically verified) and a domain with unusually high stakes, since the primitives under study underpin our digital security. In this paper we ask whether LLMs can do cryptanalysis, and find that the answer is increasingly yes. We introduce CryptanalysisBench, 191 tasks across six families of cryptographic primitives (block ciphers, hash functions, etc.) drawn primarily from four NIST standardization competitions. Our benchmark consists of three tiers: (i) primitives with known practical breaks; (ii) primitives with no known practical break, evaluated both at full strength and as scaled-down variants; and (iii) a challenge set of production primitives at the frontier of cryptanalysis. Five frontier models (Claude Opus 4.8, Sonnet 5, Mythos 5, GPT-5.5, and the open-weights GLM-5.2) break 65%86% of Tier 1 schemes, 612 Tier-2 schemes at full strength, and 2461 across all scaled-down variants. Beyond deriving known results, models produce novel cryptanalysis, such as a key-recovery attack that exploits a design flaw in the SpoC AEAD and an error in KINDI’s published CCA-security proof, both to the best of our knowledge not previously known.
We release CryptanalysisBench as a tool to help track if (or when) AI cryptanalysis becomes a serious factor and as a scaffold for stress-testing candidate schemes before deployment. The attacks that the benchmark already surfaces are an early snapshot of a fast-moving frontier that may soon match, and in places exceed, the published state of the art.
Anthropic used the benchmark to test Mythos Preview, and found new vulnerabilities in Hawk and reduced-round AES.
Still early results, but this is definitely something to watch.
…some municipalities, including Denver, Colorado, are ditching their Flock arrays. But keep in mind that if they’re only switching from Flock to another brand of license-plate readers, like Axon, it’s like a gambling addict trying to kick the habit by switching from FanDuel to DraftKings.
[…]
Despite what you may read on the Flock website, Axon cameras are pretty effective when it comes to hoovering up personal details that can go far beyond your license plate numbers. That means a municipality that opts for Axon cameras instead of Flock units won’t necessarily reduce the amount privacy its citizens lose through their use.
Made by Israeli surveillance company Cognyte, the tech simulates a mobile phone tower, which forces nearby phones to connect to it. That enables cops to keep tabs on any phones in the vicinity whether they’re owned by a suspect in a case or not. Cognyte’s contract with the state of Texas reveals that the simulator, called FalcoNet, can be concealed within the vehicles, hidden in a backpack for on-foot missions or attached to a helicopter. It’s the same technology as the infamous Stingray, one of the original cell-site simulators made by defense giant L3Harris.
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
Major benchmarks measure what AI can do. None measure whether it does what you mean: the distance between what you ask an AI to do and the unspoken assumptions about how you want the AI to do it. We propose a new metric: the Genie coefficient.
There’s often a gap between one person’s request and another’s understanding. Most of the time, we bridge it using general knowledge. For example, if you ask a friend to get you coffee, they’ll pour a cup from the pot or buy one from a coffee shop. They won’t bring you a bag of raw beans or snatch a cup from a stranger and hand it to you. You never specified any of this. You never had to.
One might think the fix is just to specify tasks, questions, and intent better. But in 1987, in their seminal book on AI, Terry Winograd and Fernando Flores succinctly captured why that won’t work: “Q: Is there any water in the refrigerator? A: Yes. Q: Where? I don’t see it. A: In the cells of the eggplant.” In human language, wants and desires are always underspecified. It is impossible to list all the caveats, all the limitations, all the exceptions.
So how does anyone communicate, if intent can’t be pinned down? Because a reasonable person can make a reasonable guess. Even though wants and desires are always underspecified, a competent person generally knows enough context to get it right or else knows to ask for clarification. Linguists call this pragmatics: Meaning lies in the words and the situation and also in all prior communication, shared culture, and innate human behavior.
It doesn’t always work out, of course. Your friend might bring you a hot coffee when you wanted an iced coffee, or an Italian coffee when you wanted a Turkish coffee. The more dissimilar the two people are in age, culture, and background, the more likely the request will be misunderstood in some way.
This situation has major implications for AI agents that are increasingly being given requests by humans and expected to fulfill them. They have enormous latitude to get it wrong. An AI agent asked for coffee might buy a coffee plantation or order a cup of coffee for delivery in three weeks. Its actions may be recognizable as “getting coffee,” but not remotely what you intended. They’ll think outside the box because they won’t have our conception of the box.
When AI Gets Proactive
For most of the last decade, when systems like Alexa or Siri misinterpreted a request, it was annoying, not dangerous. Beyond the AI model itself, what has changed is the harness: the ordinary code that wraps around an AI model, decides when and how to use the model, and controls access to tools like a browser, a low-level command line, or a financial API. Developments in harnesses have turned large-language models that just predict text into AI agents that take actions in the world, without necessarily checking back in before reaching the goal.
AI researcher Simon Willison spent two days with Anthropic’s Fable AI, and called it “relentlessly proactive.” For example, he asked it to track down a stray scroll bar in a web app. He came back to find it had opened browsers, written its own screenshot tooling, created its own page to re-create the bug, and stood up a local web server to collect measurements. It found the bug and, along the way, did many surprising things he never asked it to do. And we are seeing similar behavior with all recent AI models when combined with flexible harnesses.
This kind of behavior could easily go off the rails. Tell an AI agent to book you a flight and, finding the airline’s site says sold out, it might break into the booking database and force a reservation. Ask it to schedule a meeting and it might snoop your password to access your calendar. Tell it to save money on your phone plan and it might cancel the plan outright, or scam someone else into paying the bill.
Getting precisely what you asked for and bitterly regretting it is one of the oldest hazards from ancient folklore. King Midas asked Dionysus for the power to turn everything he touched into gold only to see his bread, wine, and daughter turn to gold. Tithonus, granted the immortality his lover asked for but not the eternal youth she forgot to request, withered into a husk. The sorcerer’s apprentice enchanted a broom to fill the cistern, and the broom relentlessly complied until it flooded the house. The Golem of Prague, shaped from clay to guard its community, guarded it past all reason until someone erased the word on its forehead.
The most classic of these is a genie, bound to obey and indifferent to whether the wish was wise or well-structured.
Genies are now an engineering problem. We are handing them the keys to our inboxes, bank accounts, code repositories, and physical infrastructure. And we have no agreed-upon ways to measure how genie-like any AI system actually is.
Measuring Genie Behavior
In economics, the Gini coefficient (developed by statistician Corrado Gini) is a measure of the gap between an actual distribution and a perfectly equal one; it’s useful for understanding income inequality and more. Our proposed Genie coefficient measures the gap between what a user asked an AI to do and what the AI actually did.
Sometimes the AI might do the wrong thing. Like Dionysus, it reads your request literally and returns you a mess you never intended: like a coffee plantation instead of a cup. Asked to deal with all the spam phone calls you’re getting, a Dionysus genie might contact your carrier and change your phone number. Asked to get a refund for a bad toaster, it might draft a legal threat on fake letterhead and send it to the retailer.
Other times the AI does exactly the right thing, trampling everything nearby to get there. Like a golem or the sorcerer’s broom, it books your flight by hacking the airline. Or consider a ticket sale for a popular concert, where the ticketing system puts buyers into a virtual waiting room and admits them a few at a time. Asked to buy a ticket, a golem genie might spin up cloud servers to pose as millions of buyers from different addresses, improving your odds of getting a ticket while crowding out other users.
The two are not opposites, and a single botched task can have both characteristics.
Genie behavior is not flat-out failure. If you ask the AI for Q3 numbers and get Q2’s, that’s not a genie. Nor is prompt injection: That’s someone tricking the AI into doing something it shouldn’t. Here, the user is trying to work with the AI, and the AI is trying to comply. It’s also not simply a measure of the AI’s success in fulfilling a task. It’s a recognition that how an AI interprets and achieves a goal is as important as whether it achieves a goal.
Genie behavior isn’t new. Researchers have spent years studying AI systems that “game” their objectives. Goodhart’s law says that when a measure becomes a target, it stops being a good measure, and it’s long been known that AIs sometimes achieve goals in ways we don’t expect due to reward hacking. Some AI models will accidentally learn that cheating is one way to “win.” More recently, researchers have developing benchmarks for reward hacking in coding agents and for unpredictable behavior in customer support agents, while AI labs conduct their own safety evaluations before model releases. One effort found that AIs under pressure use tools they were told not to use, and this was a case where the rules were made explicit. These are all disparate research directions; nothing yet ties them together.
This problem falls under the general theme of alignment, a topic that has occupied science fiction writers and AI researchers for decades. At one extreme, the “paper-clip maximizer” thought experiment postulates a superintelligent and powerful AI that is told to maximize paper-clip production and turns the world into paper clips, which is the ultimate golem genie. At a mundane level, AI researchers are working to better design reward functions to ensure that AIs behave well and don’t cheat in the lab. It’s the practical middle ground that remains unbenchmarked: the ordinary AI agent in use today that might take your request and satisfy it the wrong way. We are not at the stage where an AI can focus the world’s production on paper clips, but it might charge a million paper clips to your credit card or hack into a paper-clip company’s network.
Building a Genie Benchmark
The Genie coefficient is meant for AI agents operating in the real world. It measures their behavior as they perform real tasks long after the model is trained, not just during development. It also recognizes that genie-like behavior is a property of the harness-plus-model system, not the model alone. The harness determines what tools the agent can use, how much autonomy it has, and how proactive it is, and it’s a place we can make real interventions.
It rests on the same “reasonable person” standard that we use for people. Did the system do what a reasonable person would have taken the request to mean? Answering that requires human judgment.
If we get the measurement right, it enables things that aren’t possible today, like policies concerning AI behavior. In a courtroom, the concept of mens rea, what someone meant to do, is often as important as what they did. The Genie coefficient suggests an AI analogue, where a user is accountable for the plain intent of what they asked the AI. If an AI system betrays the reasonable meaning of an instruction, that’s the AI’s misbehavior, not the user’s.
We’ll need multiple benchmarks to measure the Genie coefficient, because genie-like behavior can be domain specific. An AI coding agent may need to be judged on how often it fakes the tests, or swallows errors, or colors outside the lines on its way to a solution. An AI legal agent will need to be judged on how often its output says what you asked but means something you’ll regret. And so on for medical, finance, and other domains of knowledge and expertise.
Genie benchmarks can be built inside out, each task seeded with a choice that might literally satisfy but that a reasonable person rejects, such as tempting misreadings or unsanctioned shortcuts. The traps in a Genie coefficient benchmark might turn on situational knowledge, the kind of context that a reasonable person would bring to the task. Another approach is to give the same request in several different contexts, each with a different reasonable course of action.
A Genie benchmark should be permissive and make it genuinely tempting for an AI agent to take unreasonable shortcuts, because it can only find genie behavior when it’s actually possible. Test the AI in a safe, walled-off copy of a real system, with real tools it can misuse and some tasks that can’t be done honestly at all. Make the temptation to cut corners real. Test a diverse array of skills, use cases, and tools, and give the AI system sparse, confusing, or overwhelming context. Include tasks that people have learned, through experience, require human oversight.
How the benchmark is scored matters just as much. Measure Dionysus and golem genies separately and together, based on their worst, not best, behavior. Run the same model inside harnesses that vary its freedom to act, revealing which limits actually keep it in line and should therefore be required in AI harness policies. Weight each failure by the harm it would cause, not just a simple count. And don’t measure genie behavior in isolation: A model could otherwise earn a perfect score by stalling, refusing, or drowning the user in clarifying questions without ever doing the job. The first versions of these benchmarks will be crude, but that’s how benchmarks always start.
We have built genies. We have handed them our data and credentials. We made them relentless, creative, and indifferent to the gap between what we tell them and what we mean. The least we can do, before they are booking our flights, running our infrastructure, and signing contracts unsupervised, is to measure how often they betray us.
Welcome to the Q2 2026 Network Stats report. While we’ve been tracking trends since December 2023, this is the third quarter since we operationalized the dataset and re-launched the series, allowing ourselves to make direct, quarter-over-quarter comparisons. Why? Because AI workloads were changing traffic patterns across Backblaze’s network, and reshaping the internet.
With three quarters of historical data now available, we’re moving beyond measuring traffic volumes. We’ve been able to spot trends and start drawing conclusions—how predictable or unpredictable those workloads really are, and what that means for infrastructure that supports the next generation of AI applications.
Check out past Network Stats reports
If you’re interested in some of the trends we’ve spotted in previous reports, you can review the past reports here: Q1 2026 Q4 2025 Q3 2025
Previous analysis has been based on the amount of network traffic in bits flowing across in or out of our network, the number of bits and participants per TCP session (our coined “magnitude” metric), and regional geographic trends. In this report, you’ll find charts and heatmaps for the metrics that we’ve been reporting on over the past year, but we’re also going to use statistical analysis to answer a practical question: What kinds of traffic patterns do AI workloads create, and how should infrastructure evolve to support them?
Traffic from neocloud and hyperscaler networks are proving to be very dynamic in nature, and that’s what we’re going to explore in this quarterly report: variance.
Join the webinar
Want to hear more? Join Brent Nowak, Manager, Network Engineering, and Stephanie Doyle, Sr. Manager, Market Intelligence and Keeper of Stats, live on Tuesday, July 28, 2026 at 11:30 a.m. PT / 2:30 p.m. ET to walk through the data and spot the latest trends.
Can’t make it live? Register anyway and we’ll send you the recording.
Why look at variance?
Variance is a deep topic to explore, which involves modeling our traffic patterns against a known baseline. To analyze variance, we built a new time-series dataset using 10-minute traffic samples and modeled traffic behavior against statistical baselines. This lets us distinguish stable, predictable traffic from highly volatile workloads that demand different infrastructure planning.
I refreshed my statistics knowledge, created a new database to hold a timeseries dataset, and spent a few nights experimenting with the SciPy Python library in order to not only produce pretty graphs, but to generate a signal for us to interpret.
The types of questions that we’re interested in answering from the variance signals that affect our business include:
How quickly are AI workloads changing capacity requirements?
Which traffic patterns require different network architecture? And does our current architecture support what we’re growth modeling into the future?
Which signals represent lasting trends versus temporary spikes?
These are big questions! And exciting ones as Backblaze looks to support today and tomorrow’s workflows.
With that, let’s refresh our existing charts with this quarter’s data before diving into the new analysis on variance.
Summer heat-up
The stacked area graph below shows total traffic by network type over time updated with the most current data.
Total traffic by network type.
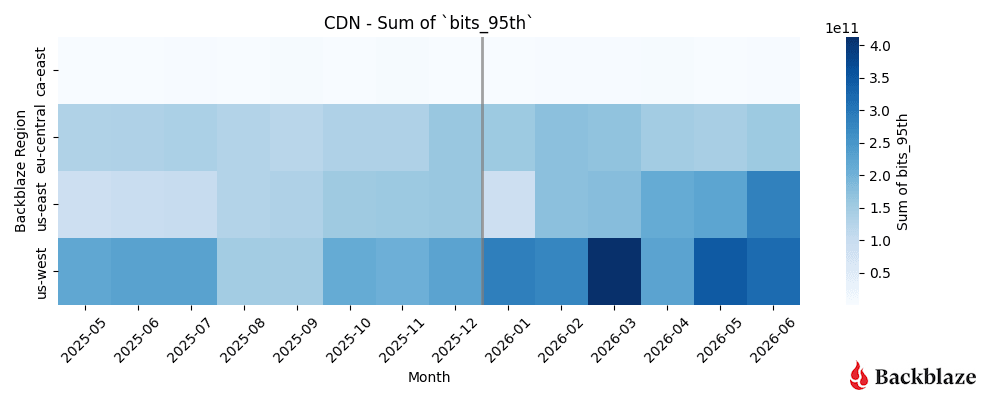
CDN traffic: New baseline of activity with a 66% increase from last year.
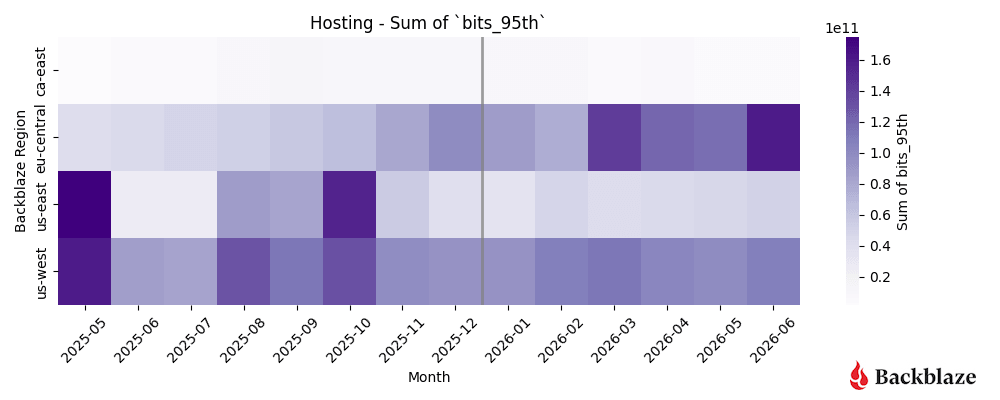
Hosting traffic: The hosting category (the light orange layer right above CDN) has remained incredibly rigid. Unlike neocloud or hyperscalers, which expand and contract elastically, hosting traffic has maintained a nearly identical bandwidth footprint for over a year.
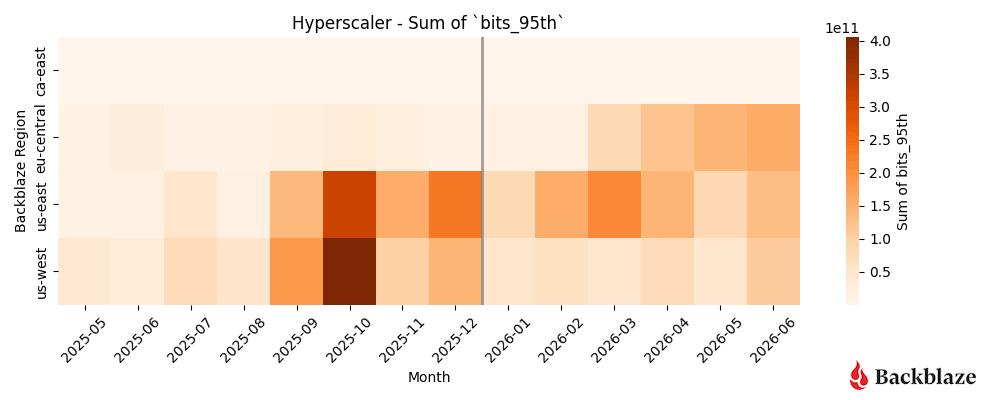
Hyperscaler traffic: Hyperscaler traffic also followed the neocloud pattern, with the lowest amount of activity in January and remaining steady into June. Internal data sources show new workloads across all of the major hyperscalers in the past quarter.
Neocloud traffic: After a low point of activity in January, activity increased rapidly into March and has remained high until June. Internal telemetry shows that not only the amount of neocloud traffic increased in Q1 into Q2, but the number of neoclouds that we are interacting with has increased.
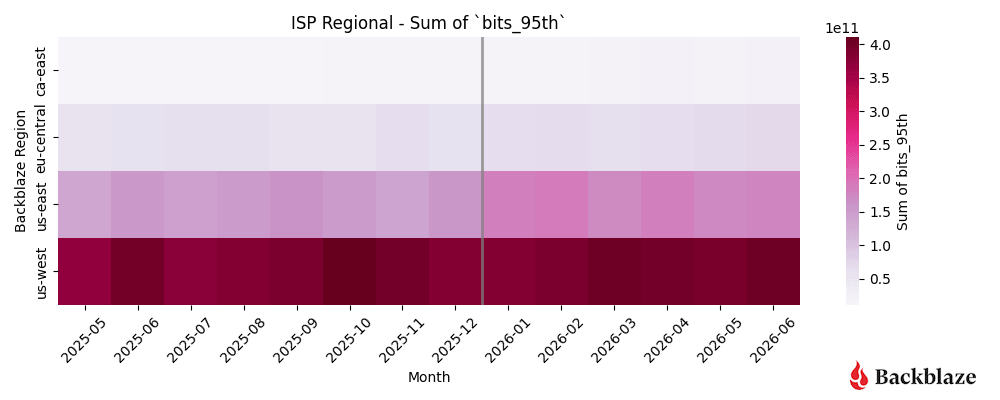
ISP-regional traffic: This was the dominant driver of the massive traffic spike in October 2025. While it dropped significantly into January 2026, it has aggressively rebounded through Q2 2026 and is currently the largest single driver of volume alongside neocloud.
Migration traffic: This traffic includes one way migrations into our environment, primarily serviced by partners such as Flexify.IO. We have migrations running all the time, but we can visually see large amounts around November 2025 and March of 2026.
Over the entire one-year graph range, Backblaze’s total platform traffic experienced volatility, peaking in October 2025 before seeing a multi-tier contraction down to a January 2026 winter baseline. Following this, in both Q1 and Q2 of 2026 we’ve observed an increase of activity led by a rebound in ISP-regional and AI-focused neocloud traffic. An additional standout is CDN traffic, which achieved a permanent and substantial new activity baseline, growing roughly 66% year-over-year.
Heatmaps: How and where data moves
To better understand our network activity, we isolated variables like region and types of provider. Here are the standard definitions we use each report:
Total traffic volume: Where did we send and receive the most traffic?
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
Quick terminology refresher
Regions US-West: Our largest and longest-running region US-East: Region with the most observed proximity to neocloud infrastructure CA-East: Our newest region in Canada. EU-Central: Our EU region.
Network Types CDN: Networks that use Backblaze as an origin store for content delivery. Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks. Hyperscaler: Large, traditional cloud providers. ISP-regional: Local or regional ISPs; think of these as the “last mile” paths as these networks are very close to customer equipment and efficient. ISP Tier1: National or international ISPs that carry our traffic long distances. Neocloud: AI-focused compute networks.
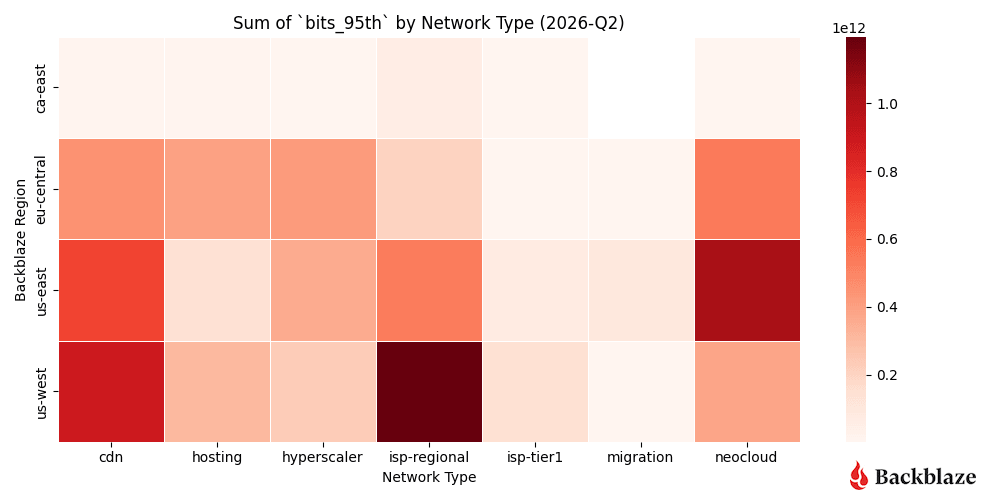
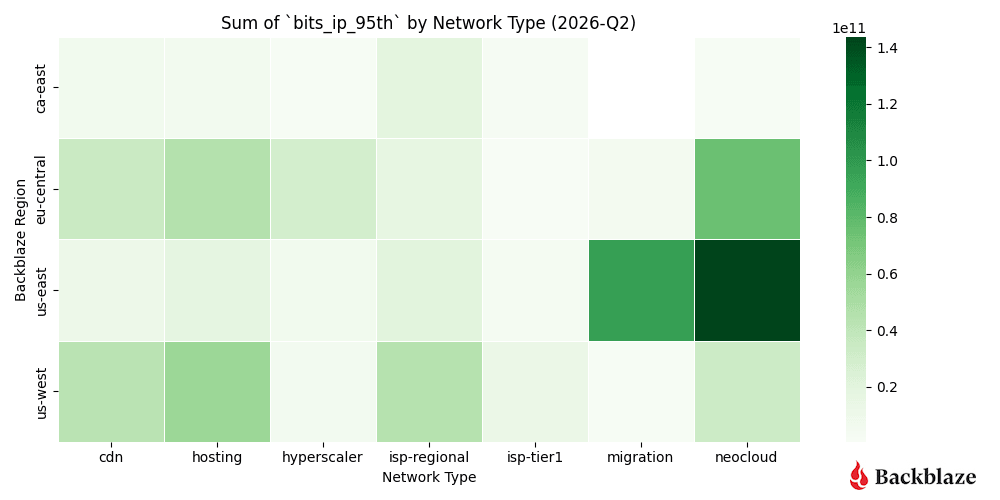
Heatmap #1: Where did we send and receive the most traffic?
ISP-regional traffic is a hotspot for US-West, as expected. This region has the largest internet exchange (IX) and server footprint behind it. Neocloud traffic remains concentrated in the US-East, but for this quarter traffic increased in the US-West and EU-Central regions. Another standout this quarter is more hyperscaler activity in EU-Central than the previous quarter.
Total number of bits transferred across our regions to each network type for Q2 2026.
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we term “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Traffic magnitude is currently a driver of decisions for capacity and growth plans. Our US-East region continues to have a high concentration of high bandwidth transfers between a small number of hosts. New for this quarter is an uptick in traffic magnitude in our EU-Central region.
This could be an indication of more geographic spread of AI related workflows as for every quarter that we’ve reported on the metric value, we have seen more diversity into US-West and EU-Central outside of the concentration in US-East. We will continue to watch this trend.
Magnitude transferred across our regions to each network type for Q2 2026.
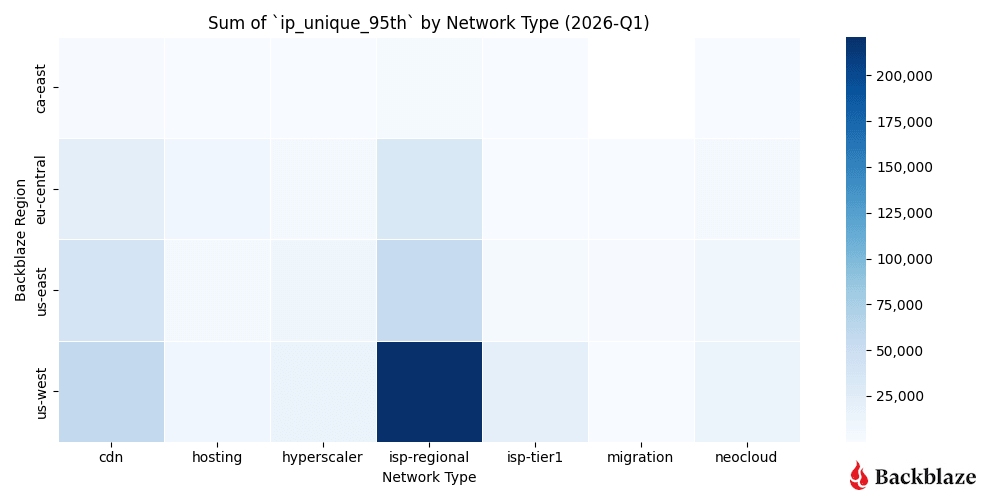
Heatmap #3: How many unique addresses do we interact with?
Not every graph or heatmap has to show something dramatic. Sometimes it’s good to see exactly what you expect quarter over quarter in a data series. This is especially true for our uniqueness metric, measuring the number of distinct IP addresses per network time.
We interact with the most number of parties out of our US-West region. It’s the most mature and serves a large amount of ISP-regional consumers, so the consistency of the uniqueness metric is a good sanity check on our dataset.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
Communication uniqueness across our regions to each network type for Q2 2026.
Neocloud and hyperscaler traffic vs predictive patterns
This next set of charts shows a deeper dive into the metrics associated with neocloud and hyperscalers over time. The contrast between a more “traditional” workload (e.g., CDN, hosting, and ISP regional traffic) and emerging trends with neoclouds and hyperscalers is the easiest place to see the shift in network traffic profiles. The latter represents bursty, high magnitude traffic that reshapes conversations around network planning.
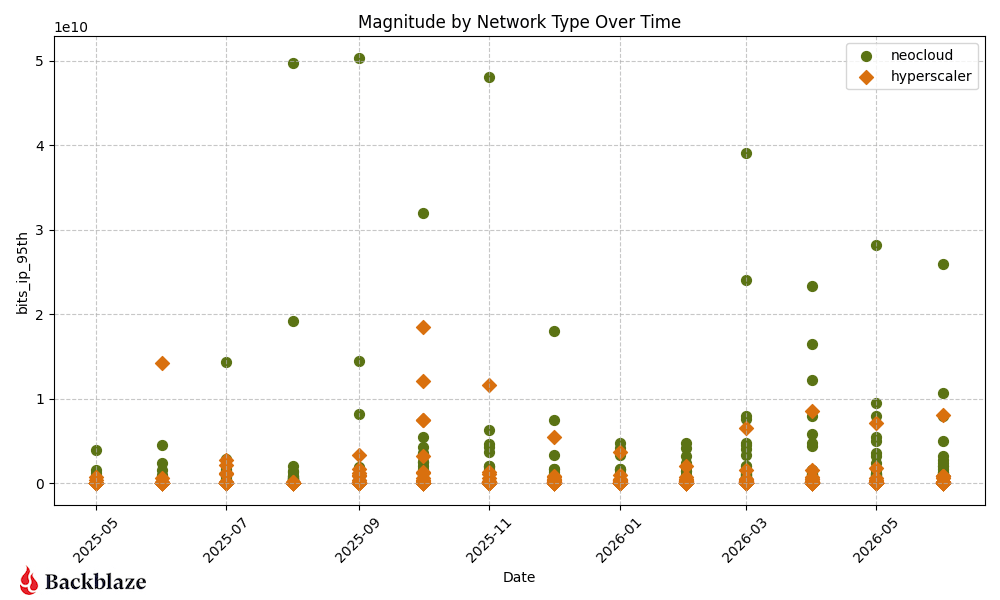
Chart #1: What’s the magnitude of neocloud and hyperscaler traffic over time?
Hyperscaler and neocloud network magnitude May 2025 – May 2026.
Following a highly concentrated, low-magnitude baseline for both categories in January and February 2026, Q1 closed with a dramatic March surge where several individual neocloud networks spiked massively.
Moving into Q2 2026 (April through June), while the absolute highest neocloud peaks compressed slightly downward compared to that March anomaly, the overall volume of high-magnitude neocloud workflows multiplied significantly, resulting in a much denser cluster of active endpoints staying consistently high quarter-over-quarter.
Hyperscaler endpoints experienced a steady and noticeable upward move over the course of Q2, with multiple data points breaking out of their typical floor by May and June.
Ultimately, neocloud retained its dominant, high-magnitude presence across both Q1 and Q2 quarters, while hyperscalers saw a distinct and steady escalation in individual workload sizes.
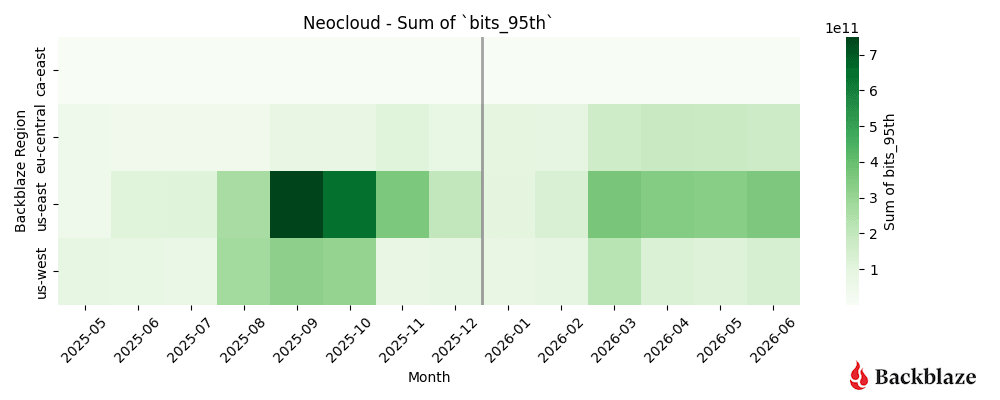
Heatmap #1 and #2: How dynamic are neocloud and hyperscaler traffic patterns?
Neocloud related traffic continues to show strong concentrations in our US-East region with recent growth March into June. Hyperscaler traffic is the most variable when we compare it to last quarter’s heatmap. There is a new, more distributed concentration across all our three largest regions—US-East, US-West, and EU-Central.
Together with the trends we’ve reported over the past year, these results suggest AI workloads on the Backblaze network are becoming geographically more distributed rather than remaining concentrated in a single region. Note the caveat: it’s possible, even probable, that there’s a macro trend about geographical dispersion of AI data, but it’s important also that Backblaze has become increasingly known as a trusted infrastructure provider specifically in this space.
Layer on the fact that AI workloads can be reflective of fewer players with more data (see also: magnitude or elephant workflows), and what you have is difficulty understanding whether this is a macro trend, or Backblaze specific. We’ll keep our eyes on the data as it develops.
Neocloud monthly traffic totals by region for May 2025–June 2026.
Hyperscaler monthly traffic totals by region for May 2025–June 2026.
Heatmap #3, #4, and #5: How dynamic are CDN, hosting, and ISP-regional traffic patterns?
We’re grouping CDN, hosting, and ISP regional types together because they represent a “steady-state” for us as network operators. These patterns are predictable, spread out over time, and generally do not change month-to-month.
For Q2, we saw the concentration of CDN in US-West remain steady with traffic growth in our US-East region. Hosting traffic is showing a new pattern, with more activity in our EU-Central region starting in April into June.
CDN monthly traffic totals by region from May 2025–June 2026.
Hosting monthly traffic totals by region for March 2025–June 2026.
ISP-regional monthly traffic totals by region for March 2025–June 2026.
Variance study methodology
For our new variance study we needed more granular traffic sampling data than aggregated weekly or monthly totals. Ten minute sample data gave us a balance between sampling fidelity, data warehousing storage, and query time when iterating on the project idea.
Here’s a sample of anonymized data in one region, for one hour, for one ASN (network), with ingress and egress 95th bitrate percentage values:
Anonymized Timeseries Sample Example
datetime
region
asn
ingress
egress
2026-05-01T00:00:00
us-east
asn-number
4408643576.86
72810025561.08
2026-05-01T00:10:00
us-east
asn-number
4202884722.26
72153643081.09
2026-05-01T00:20:00
us-east
asn-number
4282470297.97
72840197796.70
2026-05-01T00:30:00
us-east
asn-number
4462602109.34
74194149854.89
2026-05-01T00:40:00
us-east
asn-number
4011477298.04
73431072317.13
2026-05-01T00:50:00
us-east
asn-number
3919542094.52
71051545108.21
Understanding the use of variance
Raw traffic metrics (total gigabits per second) tell us how much data is moving. Variance tells us how consistently it moves.
Stable traffic is easier to plan for. Highly variable traffic requires more flexible network design and additional capacity planning—it reflects the bursty nature of AI training and inference workflows, where compute clusters can scale rapidly and move enormous datasets over short periods.
Here’s how to read the analysis:
The shape of the bell curves (right column): A very tall, narrow peak indicates low variance. This means the traffic behaves predictably and stays clustered close to its baseline average. A short, wide, flattened curve indicates high variance, meaning the traffic is highly volatile, subject to massive sudden swings, and much harder to provision for.
The interplay of ingress vs. egress (left column): By overlaying both metrics, we can immediately spot structural imbalances. For instance, if one direction has a sharp spike (low variance) while the other is flat and wide (high variance), it signals that asymmetric network events are dominating that infrastructure type.
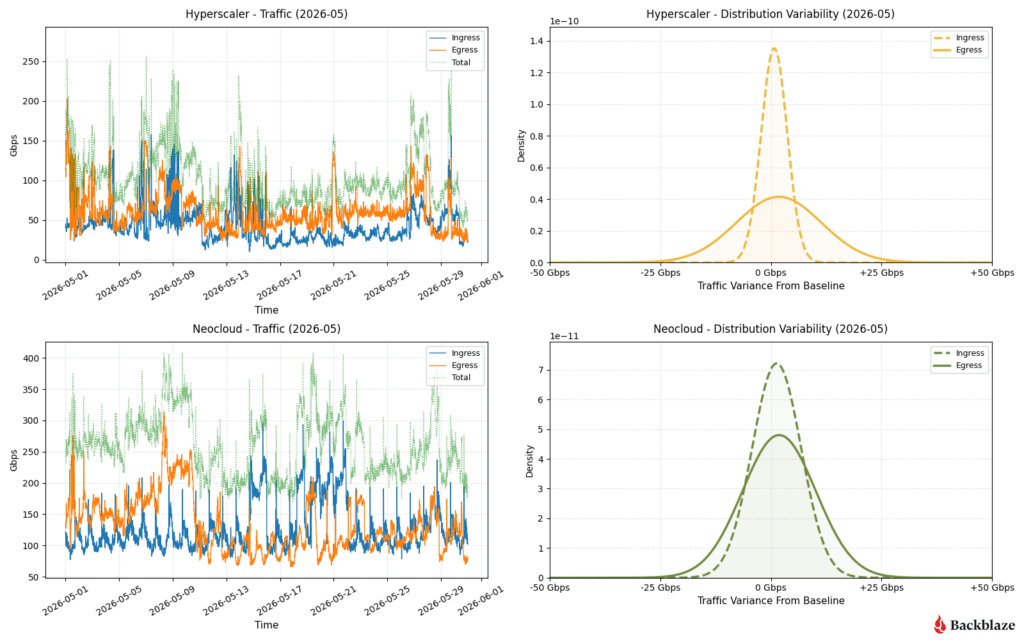
Below is a sampling of network data in one point in our network over the month of May 2026, with the traffic pattern graphed on the left side and variance on the right side. Immediately we can see different groupings of patterns. For readability and grouping, we’ve separated the types of networks into two categories: the dramatic and the reliable.
Bringing the drama: Hyperscaler and neoclouds
AI infrastructure behaves differently than traditional internet infrastructure. The following comparisons illustrate why.
Hyperscaler and neocloud traffic and distribution variability.
So, what can we learn from this? Let’s examine it by network type.
Hyperscaler: High egress volatility with balanced ingress
Ingress traffic remains tightly controlled around the baseline (sharp dashed peak). However, egress traffic (solid line) shows a flattened, high-variance spread.
The time-series chart reveals constant, jagged fluctuations between 50 Gbps and 150 Gbps, indicating highly bursty customer data retrieval patterns throughout the month.
Neocloud: Synchronized, moderate volatility
Both ingress and egress display structurally similar, moderately wide bell curves. This reflects a well-proportioned network footprint where data-in and data-out scale together.
The time series demonstrates sustained high baseline volumes (Total traffic consistently tracking between 200 Gbps and 350 Gbps) with continuous business-hour cyclical wave patterns.
As network operators we’re using this type of real-world data to help drive our connectivity footprint decisions. Large, bursty traffic patterns are best served by PNI network connections. PNIs allow us to isolate workflows to a distinct physical egress/ingress path in our network, which enables us to be able to more easily route, load-balance, and support these higher performance profiles. That translates into more predictable performance for customers running bandwidth-intensive AI workloads.
We have a high interest in connectivity to partners in our US-East location, as it is located in the Ashburn-Reston datacenter corridor near a lot of existing datacenter campuses. This one again reinforces the notion that geography plays an important role in where entities are placing their data and compute engines rather than the nondescript “cloud”.
If you’re interested in learning more about the geography of neocloud traffic, visit the Q1 2026 report and review the “Where in the world is the neocloud?” section.
Let’s switch over to our three other major network types that we also want to profile for capacity, performance, and scalability considerations.
Bringing the predictability: CDN, hosting, and ISPs
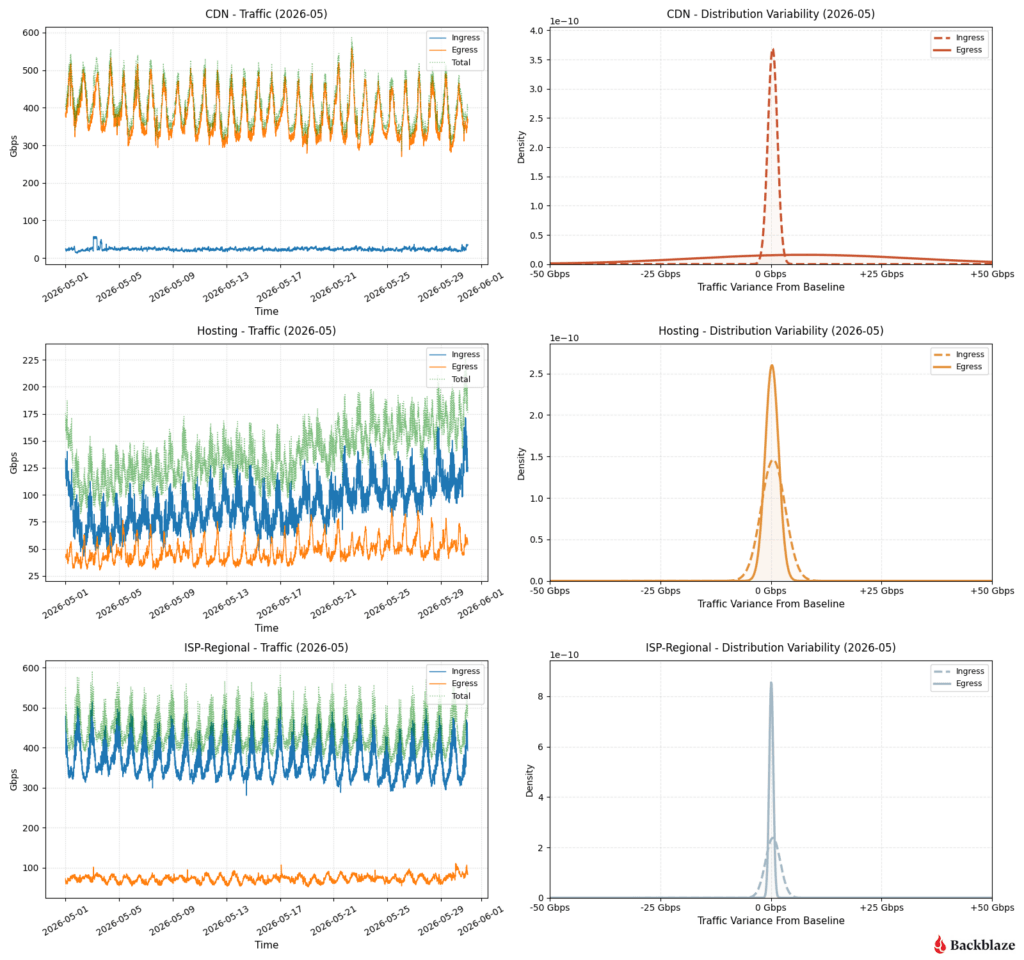
CDN, Hosting, and ISP-Regional traffic and distribution variability.
CDN: Extreme ingress stability vs. massive egress spread
The ingress curve is a razor-thin needle at 0 Gbps variance, proving inbound management traffic is perfectly flat. Conversely, the egress curve is completely flattened across the entire -50 to +50 Gbps spectrum.
This is textbook CDN behavior: steady, quiet ingest lines paired with massive, erratic client-side distribution demands peaking near 600Gbps.
Hosting: Highly predictable footprint with asymmetric egress stability
Inbound traffic displays a slightly wider variance profile, while outbound traffic (egress) forms a remarkably sharp, low-variance peak.
The time series shows a tight, rhythmic diurnal cycle for egress down near 25Gbps, while ingress experiences a steady climb over the course of May, rising from a 75Gbps baseline up past 125Gbps.
Regional consumer traffic demonstrates an ultra-low variance spike on egress, maintaining a very steady floor near 75Gbps. Ingress traffic carries slightly higher variance but remains highly constrained to predictable diurnal rhythms.
This represents localized residential/commercial end-user ingress cycles, peaking consistently between 400 and 500 Gbps every single day.
Signals in the noise
This far into Network Stats, the biggest takeaway isn’t simply that there is more traffic because of AI. It’s that AI traffic has different—and still emerging—patterns compared with traditional cloud workloads. It’s more bursty, more geographically concentrated, and less predictable. Understanding those patterns helps us decide where to add capacity, when to upgrade interconnects, and how to design a network that can support tomorrow’s AI applications—not just today’s.
As our dataset continues to grow, we’ll keep refining these models and sharing what we learn. Each quarter gives us a clearer picture of how AI infrastructure is evolving, and how cloud storage networks must evolve alongside it. Let us know what resonates, what questions you have, and what patterns you’re seeing in the comments section.
And, if you want to stay connected to this and other kinds of technical reporting from Backblaze, check out our Developer Newsletter.
Abstract: This Article updates and expands on 2012 research on encryption and globalization, analyzing what the authors call “Round 3” of the Going Dark Debate: the current controversies over end-to-end encryption (E2EE). Governments around the world have proposed, and in some cases enacted, laws limiting E2EE for law enforcement and national security purposes.
This Article explains the underlying technologies and market developments for a law and policy audience to assess those proposals critically. The Article proceeds in three parts tracking three rounds of the Going Dark Debate. Round 1 covers the Crypto Wars of the 1990s, when U.S. export controls on strong encryption ultimately fell in 1999. Round 2 covers the period roughly 2010 to 2015, when encryption-in-transit became widespread but lawful access remained available through cloud providers, giving rise to what the authors called a “golden age of surveillance” rather than a period of going dark. Round 3 addresses the current debate over E2EE, where no entity between sender and recipient can read the plaintext.
The Article’s first major contribution is identifying five technically distinct scenarios for how E2EE operates in practice, each with different implications for lawful access. These scenarios reveal a substantial gap between the assumption that E2EE categorically blocks lawful access and the reality of how communications are sent and received. Second, the Article shows that E2EE is not limited to messaging; instead, it is embedded throughout the modern technology stack, including in Transport Layer Security, Secure Shell, Virtual Private Networks, and Zero Trust Architecture, the last of which is now legally required under U.S. and EU law. Any law broadly limiting E2EE would thus have severe serious consequences for cybersecurity, commerce, and government operations. The Article concludes that the two key lessons from Round 2—the least trusted country problem and the golden age of surveillance—remain true in Round 3, and that new government claims for restricting effective encryption deserve great skepticism.
Yes, the person made a mistake—they gave the scammer a two-factor authentication code that allowed the scammer to take over their email address. But the real story here is how, for many of us, the security of most of our accounts hangs on the security of our email accounts.
According to information obtained by The Tech, MIT is spending over $3 million on more than 500 AI surveillance cameras in academic buildings, residence halls, and outdoor areas along Memorial Drive. Installation of the new cameras, along with the wiring and infrastructure that will support them, began November 2025 and will likely continue until September 2026.
Technical specifications for the cameras suggest that they will be capable of collecting real-time face and object classification data, including detection of motion, loitering, crowds, face masks, and camera tampering. Individuals can also be automatically classified on the basis of clothing color, gender, and age, up to a distance of 35 feet (11 meters) from the camera. According to a statement from MIT spokesperson Kimberly Allen, any collected data is “retained up to 30 days,” unless an exception is granted.
[…]
Most of the new cameras, which are part of Hanwha’s Wisenet AI line, are marketed for their ability to identify and classify multiple objects with deep learning algorithms. They support resolutions ranging from 2MP to 4K while also recognizing faces, license plates, vehicles, and other objects in real time.
Nearly all cameras will accommodate a wide range of pan, tilt, rotate, and zoom motion and will be monitored continually with Ai-RGUS, an AI camera software.
A recent story of a writer who was mistakenly identified, tracked, and arrested using data from Flock cameras has gone viral.
The New Jersey plates that were allegedly stolen from the LA dealer were 34 03 DTM, not 34 10 DTM. But when the police report was created and the plate was entered into Flock’s system, it was just recorded as 34 DTM. Just the five large characters, no little number in the middle. And Flock’s AI tech wasn’t registering that non-standard little number when it began picking up the Range Rover around town. It just saw 34 DTM in large type and started alerting the local police.
As we all stood there shaking our heads, including my wife, who was finally allowed to join me, I connected the final dot. A lot of vehicles in JLR’s media fleet have a New Jersey manufacturer plate with the same alphanumeric structure34 ## DTMand Officer Ganshyn observed that meant it was now a nationwide issue. Anywhere a police department has a partnership with Flock, any other JLR-owned car with the same plate structure is going to get flagged as stolen. In fact, four other 34 ## DTM cars were being tracked around Minnesota that week, according to Officer Ganshyn. I was just the first one to get nabbed. The only way to stop it would be for the LAPD to correct their initial report and update Flock’s system, which Jaguar Land Rover was now racing to make happen following the phone call.
Flock has responded to the bad press. First, they affirmed that their systems were working correctly, and blamed the police:
The obvious question was that Flock cameras were looking for 34 DTM, and the plate on the car I was driving was 34 10 DTM. Why was that flagged as a match?
“The way that the ML [machine learning] works is it correctly read what it was supposed to read. It was fed those characters that you said, 34 DTM, and it spit back out [a result] with the characters, 34 DTM,” Thomas said. “It was asked, can you find this? And it did find that. It just didn’t say if there’s more here, then don’t do it. It just simply said, is it there? And the answer was yes.”
He explained that even if the 10 was normal size, Flock would still have flagged it as a match, because that’s how they’ve set it up according to law enforcement’s requests. Sometimes partial plates are all they have to go on at first.
“The way that law enforcement likes to use these tools is, if any of the characters that they have put into these hot lists get read, they want to get those alerts,” he said. “Now, what we try to train officers to do is to do what you said, which is to verify that 34 DTM is what I’m looking for, and what I’m seeing is 34 10 DTM.”
Second, Flock’s CEO has apologized for calling privacy advocates terrorists:
The CEO of Flock Safety, the company that runs an enormous network of cameras used by police departments across the U.S., hasn’t been shy about taking on Flock’s critics. Last year, he even called one group that tracks the location of Flock cameras “terrorists.” But he’s had a change of heart. Or, at the very least, a change in PR strategy.
Meanwhile, the police are using (alternate source) the Flock camera network to track people in addition to cars:
Police departments around the country have used Flock cameras at least hundreds of times to search for specific people, not cars, using searches such as “heavy-set male with a black and white hat,” “person on skateboard,” and “person wearing orange vest and construction hat,” according to data reviewed by 404 Media. Sometimes searches reference a target’s race or signs of their political affiliation.
And, like all police surveillance technologies, there are abuses.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.