Accounts move between organizations in AWS Organizations whenever a business changes shape. A merger folds one estate into another. A divestiture carves one out, and some companies run more than one organization by design.
The moves take more care when AWS Resource Access Manager (AWS RAM) resource shares are involved. An organization-bound share trusts an account through its organization membership, so when the account leaves, AWS RAM removes that association. Anything in production that depends on a shared resource needs a continuity plan before the first account moves.
A leading worldwide provider of payment technology and software solutions, based out of the United States, used temporary AWS RAM resource shares to preserve AWS Lake Formation permissions during an AWS Organizations migration of 382 AWS accounts. The payment processor serves merchants and financial institutions around the world. The program separated them from their former parent company, a US-headquartered financial technology provider serving banking and capital markets clients globally, before a Transitional Service Agreement (TSA) expired in April 2026.
The migration unfolded alongside wider corporate change. In January 2026, the payment processor was acquired by a leading payments technology company headquartered in the United States. The transaction transforms the acquirer into a pure-play commerce solutions provider, serving the full spectrum of clients from small businesses to global enterprises worldwide. The migrating estate also included the payment processor’s embedded payments platform, a US-based provider of embedded payment and automated onboarding tools for software-as-a-service (SaaS) platforms.
Most workloads kept running when the original organization-bound shares broke, but the control plane lost access. They needed a migration pattern that preserved service continuity without leaving temporary permissions behind.
AWS partnered with them to design and validate that pattern in two weeks. It uses retained bridge shares for the move, then restores the original shares as the durable permission objects.
An AWS account can consume a resource to share automatically while it belongs to the same organization as the producer. When the account leaves, AWS RAM removes that organization-bound principal association. Creating a retained bridge share as an external association before the move preserves access through the organization’s change.
After the move, the company restores the migrated account to the original share, verifies access, and removes the bridge. The original share remains the AWS Lake Formation-managed source of truth. New grants and resource changes continue to attach to it, not to the point-in-time bridge copy. Keeping both would create duplicate permission state and drift.
The following diagram shows the migration wave structure.
Migration wave structure. Stage one covers fourteen non-production waves across eight months, none of which crossed an organization boundary. Stage two covers sixteen production waves: one pilot wave, twelve scheduled waves on a weekly cadence, and three contingency waves. The transitional service agreement expires inside the contingency window, leaving only the first contingency week usable.
The company’s cloud engineering team ran 14 non-production waves, a production pilot, 12 weekly production waves, and three contingency waves. The TSA expired inside the contingency window, leaving about one week of usable slack.
Challenge
The risk surfaced in a production wave in February 2026. A terraform apply against a shared AWS Transit Gateway failed with a permission error, although traffic kept flowing and no alarm fired.
This was a control plane failure. Existing attachments, DNS paths, and certificates continued to work, but engineers could not change shared resources. The dedicated AWS Transit Gateway, Amazon Route 53 Resolver, and the embedded payments platform’s AWS Glue Data Catalog waves were still ahead.
Why the issue stayed hidden
Most services retain their data plane when an AWS RAM association breaks. For example, an Amazon Elastic Compute Cloud (Amazon EC2) instance in a shared Amazon Virtual Private Cloud (Amazon VPC) keeps running, but the account cannot launch a new instance. Infrastructure-as-code exposed the problem because it needed control-plane access.
The following table summarizes the affected resource types confirmed by the customer.
Keeps the data plane, blocks new resource creation
AWS Glue Data Catalog databases and tables
AWS Glue and AWS Lake Formation
Requires bridge-share validation before migration
Some services require additional handling. Depending on its resource-cleanup configuration, an AWS Firewall Manager policy can remove AWS Network Firewall rules, which you must then redeploy, and organization-integrated AWS CloudFormation StackSets can delete stacks unless you set them to retain.
The embedded payments platform initially entered the estate through an acquisition by the former parent company. Its embedded payment and automated onboarding capabilities were subsequently integrated into the payment processor’s ecosystem to support a broader platform-focused offering for SaaS providers. The platform shared databases and tables across 10 accounts with account IDs as principals, and the workstream was paused rather than testing the migration against production.
Why the original shares broke
The company had enabled sharing with AWS Organizations in the producer account. AWS RAM therefore trusted each in-organization principal through organization membership, even when a share named an account ID. When an account left the source organization, AWS RAM removed that organization-bound association.
A share created for a principal outside the organization behaves differently. AWS RAM sends an invitation, and the accepted association is external. Because it does not depend on organization membership, it survives the account move. The bridge-share pattern uses this behavior.
Why non-production testing missed it
The company’s non-production accounts were already in a separate organization. They never crossed the boundary that caused production associations to break.
Fourteen clean waves validated the migration process but not the production-only condition. Each validation environment must cross the same trust boundary as production.
Applying the bridge-share pattern
This failure was raised with the AWS account team, which brought AWS RAM, AWS Glue, AWS Lake Formation, and AWS Organizations service teams into the response. The company first used a manual recovery path for 21 accounts while the teams automated a scalable approach.
On February 27, 2026, AWS released RetainSharingOnAccountLeaveOrganization for new AWS RAM resource shares. The setting marks principals as external after they accept the invitation. The customer confirmed that the setting does not retrofit existing shares, so those shares needed a temporary parallel share.
Retaining access during the move
AWS RAM allows a resource to belong to more than one resource share, so a parallel share can exist alongside the original. A second retained share was created alongside each original, targeting the same consumer account.
The consumer accepted the invitation before migration, creating an external association. During the move, AWS RAM removed the original organization-bound association while the bridge continued to grant access. AWS Organizations also support transferring an account directly between organizations, so the move itself does not require an intermediate standalone period.
Why restore the original share?
The bridge is a migration-only continuity copy. The original AWS Lake Formation-created share remains the durable, service-managed permission object. If a team adds a grant or changes a shared resource during the migration window, that change applies to the original share, not automatically to the bridge.
The company therefore restored migrated principals to the original share before deleting the bridge. Leaving both in place would create two permission paths that can diverge, complicate audits, and conceal which share is authoritative.
Automation deletes a bridge only after it finds a non-bridge original whose resources, principals, and permissions cover the bridge and whose associations are all ASSOCIATED. This check confirms the original share’s associations are active before removing the temporary path. Access and connectivity were validated separately, as described in the Outcome section.
Validated workflow
AWS validated the pattern across three test accounts and two organizations before it was used in production. Testing confirmed that allowExternalPrincipals alone was not enough. The bridge also required retainSharingOnAccountLeaveOrganization.
The following diagram shows the bridge before and after the account move.
Bridge share behavior before and after an account moves between AWS Organizations. Before the move, the original organization-scoped share and the accepted bridge share both grant access. After the move, the original share is revoked and the accepted bridge share continues to grant access.
Each production wave used five steps:
Inventory. Map each original share, resource, principal, permission, and Region. AWS RAM is Regional, so repeat the inventory in every in-scope Region.
Create and accept bridges. Create a retained share for the same resource and principals, then accept its invitation from each consumer account before migration.
Migrate. Move the account. AWS RAM removes the organization-bound association, while the accepted bridge keeps access active.
Restore originals. Add the migrated account IDs back to the original shares as external principals. This reactivates the durable shares and includes grants created during the migration window.
Validate and remove bridges. Confirm resources, principals, permissions, and association status, then delete only bridge shares fully covered by active originals.
This workflow ran for every remaining production wave and kept the weekly cadence.
Validating AWS Glue and Lake Formation permissions
The embedded payments platform shared AWS Glue Data Catalog databases and tables across 10 accounts, with account IDs as principals. The configuration was reproduced in disposable accounts, and the resource policy was recorded through a cross-organization move.
The validated automation records principal-to-share mappings, supports dry-run and execute modes, restores principals to the original shares, and deletes bridges only after validation. The embedded payments platform completed its production migration on July 21, 2026.
Outcome
The global payment processor migrated 378 of the 382 accounts into its landing zone. The final four awaited approvals from external stakeholders.
The TSA with the former parent company ended on schedule in April 2026. No customer-facing workload lost availability, and the company recorded no network drops across the production waves. The company and AWS moved from discovery to a validated bridge-share pattern in two weeks.
After each migration, the cloud engineering team restored the original shares, verified access and connectivity, and removed the bridges. Deleting the temporary copies confirmed that the original service-managed permission path was active and authoritative.
Production, non-production, and the embedded payments platform now run in one landing zone. They control their own guardrails, security posture, provisioning, and change process.
AWS has published the validated pattern and automation, so other organizations can start with a tested procedure.
Lessons learned
This program produced three lessons for organizations planning similar migrations.
Match validation boundaries to production
A test organization cannot expose this failure unless it crosses the same organization boundary as production. Map each production risk to an environment that can reproduce it before the first wave.
Monitor control plane changes
AWS RAM emits resource share state-change events directly to Amazon EventBridge, and AWS CloudTrail records DisassociateResourceShare API calls for audit. A weekly post-migration sweep provided a periodic reconciliation check to catch stale shares.
Inventory dependencies and destination guardrails
The Account Assessment for AWS Organizations tool inventories AWS RAM dependencies before teams set the wave plan. The company’s cloud engineering team reviewed destination guardrails at the same time. A service control policy that blocked ram:AcceptResourceShareInvitation during migration windows was temporarily adjusted.
Conclusion
The migration of this leading payment technology and software company shows how a retained bridge share can protect access while an account moves between AWS Organizations. The bridge is temporary: restoring the original share keeps AWS Lake Formation permissions aligned with future grants and avoids two sources of permission state. Inventory, dry-run-first automation, and post-move validation helped the company meet its deadline without customer disruption.
The following is the Terraform-based reference architecture used to represent the solution, including EventBridge, DynamoDB, and Lambda across a multi-account environment. Relevant launch events are tracked in EventBridge that invoke Lambda functions, which are logged in DynamoDB tables (see sample code). This allows reporting on captured event data through the AWS SDK for Python (Boto3). Figure 1: Reference architecture for reporting solution on AWS Outposts
Prerequisites
The following prerequisites are necessary to implement this solution:
At least two active AWS accounts in the same AWS Organization as the Outposts owner account.
One AWS account, which is the data collection account to store the event data (this doesn’t have to be the account that owns the Outposts).
Workload accounts where resources are deployed on Outposts.
Terraform installed on the same administrative instance. For more information, see the Terraform documentation.
Make sure that you have the necessary AWS Identity and Access Management (IAM) permissions necessary to create the AWS resources using Terraform in all accounts.
Prior Experience with Terraform deployments on AWS Cloud. To increase your familiarity, you can explore Get Started – AWS on the HashiCorp website.
Step 5: Modify the variables.tf.From the root directory of the cloned repository, modify the variables.tf file with the target Region and workload accounts as shown in the following example. The target Region is the collection destination.
variable "aws_region" {
  description = "AWS region for resources"
  type        = string
  default     = ""
}

variable "allowed_account_id" {
  description = "AWS account ID allowed to put events to the event bus"


}
Initialize the configuration directory of the data collection account to download and install the providers defined in the configuration by running the following command:
terraform init
All resources are deployed with minimal permissions to serve as an example. We recommend viewing all configurations to make sure that they meet your organizational security policies. Step 6: Deploy infrastructure in the data collection account.Run terraform plan on the configuration to and review which resources are created:
terraform plan
When you have reviewed the plan, run the following command and enter “yes” to accept the changes and deploy:
terraform apply
Deployment should take less than 5 minutes. If you receive any errors, review the previously mentioned steps to ensure that you followed them in their entirety. If the errors persist, reach out to AWS Support for additional guidance.
Deploying in workload account
The data collection account receives events from EventBridge and performs intelligent analysis and storage from the AWS Outposts resource data.Step 1: Navigate to the workload account directory by running the following command:
variable "aws_region" {
  description = "AWS region for resources"
  type        = string
  default     = ""
}

variable "event_bus_arn" {
  description = "target event bus arn"
  type        = string
  default     = ""
}
Edit the code to update the event bus name.
Step 3: Run the following command to create the backend.tf and create the Terraform state bucket for each workload account.
./init-backend.sh
This is an idempotent operation that creates a file from the template and a bucket with a fixed name including the account ID if it doesn’t exist.
Step 4: Initialize the configuration directory of the Data Collection Account to download and install the providers defined in the configuration by running the following command:
terraform init
Step 5: Deploy the infrastructure in the Data Collection Account.Run a terraform plan on the configuration and review which resources are created:
terraform plan
After you have reviewed the plan, run the following command and enter “yes” to accept the changes and deploy:
terraform apply
Deployment should take less than 5 minutes. If you receive any errors, follow the troubleshooting steps in the previous section.
At this point, any Amazon EC2 or Amazon RDS instances and Amazon EBS volumes are logged to the DynamoDB tables in the data collection account. Repeat Steps 3–5 for each workload account running resources on AWS Outposts with appropriate account credentials. If you’re deploying at scale and using AWS Control Tower consider using AWS Control Tower Account Factory for Terraform (AFT).
Running monthly reports
With this solution in place, reports can be generated on demand. These reports can be customized by modifying the Python example scripts shown to support your needs. Reports can be created from a local machine with credentials that have access to the DynamoDB tables in the data collection account. The examples were created from the source directory of the data collection account git repository. Run the following command to view the report for Amazon RDS usage in September 2025:
Complete the following steps to clean up the resources that were deployed by this solution. For each workload account, complete the following:
cd sample-outposts-monitoring-and-reports/workload_account
terraform destroy
Enter “yes” to proceed. You can then manually empty and remove the terraform state S3 bucket for that account.
For the data collection, complete the following:
cd ../data_collection
terraform destroy
Enter “yes” to proceed. You can then manually empty and remove the terraform state S3 bucket for that account.
Conclusion
Customers who have shared multi-account Outposts deployments can use this solution to create account level reporting for Outposts resources using real-time event capture and processing, state analysis and categorization, historical usage metrics, and serverless architecture. Teams can use this to visualize and report on the costs of running their workloads on Outposts. The event-driven design supports accurate tracking while maintaining low operational overhead. The solution scales effectively across multiple Outposts and accounts, providing a unified view of hybrid infrastructure. Keep in mind that you can extend the functionality described here to meet your business objectives.
Deploy this solution today using the GitHub repository to gain financial insights to share with the tenants of your Outposts workload accounts. Reach out to your AWS account team, or fill out this form to learn more about Outposts.
Do you need to send SMS across multiple AWS accounts? Or have you ever wanted to use the same specific 10DLC phone number or branded Sender ID across those accounts? Perhaps your development team needs to test an application in a sandbox account using a production-ready number, or you’re migrating a workload to a new account and need to ensure your customer communications aren’t disrupted. Centralizing your messaging resources across accounts improves efficiency and branding, while lowering the risk in compliance gaps..
In this step-by-step guide, we will show how to solve this challenge by sharing your AWS End User Messaging resources across multiple AWS accounts using AWS Resource Access Manager (AWS RAM). By creating a single sharing account for your messaging resources—like phone numbers, Sender IDs, and opt-out lists—and securely sharing them with your other “consuming” accounts, you can build a more efficient, secure, and scalable communication platform.
Common Use Cases for Resource Sharing
Important: resource sharing with AWS RAM is a regional feature. You can only share resources with accountswithin the same AWS Region where those resources are located.
Centralizing and sharing resources is a powerful pattern that addresses several common customer needs:
Testing in a Sandbox Environment: Allows development teams to test applications using production-ready phone numbers or Sender IDs in an isolated sandbox account, without giving them access to production configurations.
Simplified Registration and Onboarding: Share an existing pre-registered 10DLC number or Sender ID with a new account that has not yet completed its own registration process, enabling it to start sending messages more quickly.
Seamless Account Transitions: When migrating an application or workload to a new AWS account, you can share the existing origination identities. This makes certain that your phone numbers and Sender IDs remain consistent during the transition, preventing any disruption to your customer-facing communications.
This guide will walk you through the step-by-step process of sharing your AWS End User Messaging resources.
Shareable AWS End User Messaging Resources
You can share the following AWS End User Messaging resources using AWS RAM:
Phone Numbers: Share your dedicated short codes, 10DLCs, long codes, and toll-free numbers. This allows different accounts to send messages using a centralized pool of numbers.
Sender IDs: Share alphanumeric sender IDs to maintain consistent branding in one-way SMS messages across your accounts.
Opt-out Lists: Centralize your opt-out management to ensure regulatory compliance. When a user opts out of messaging from one account, they are opted out across all accounts using that shared list. This is especially powerful when used with pools, as you can associate a pool with a specific opt-out list, ensuring all numbers in that pool adhere to the same primary list. As a best practice, you should create and share a dedicated opt-out list rather than relying on the default list for each account.
Pools: Share your pools of phone numbers and sender IDs to manage origination identities at scale. Pools provide benefits like automatic failover and apply settings like opt-out lists or two-way SMS configurations to the entire pool.
Important:for a shared Opt-out list or pool to be functional, all of its member resources (the phone numbers and/or Sender IDs within it) must also be included in the same AWS RAM resource share.
Understanding AWS RAM Fundamentals
Before sharing your End User Messaging resources, it’s essential to understand the core concepts of AWS RAM.
Resource Share: This is the central component in AWS RAM. A resource share consists of three elements:
The resourcesto be shared (such as phone numbers, or opt-out lists).
The principals (AWS accounts, OUs, or an entire organization) with whom you are sharing.
The managed permissions that define what actions the principals can perform on the shared resources.
Important: The supported resources of AWS End User Messaging are shareable with AWS accounts, Organizations, and OUs, but not with individual AWS Identity and Access Management (IAM) roles or users. This restriction ensures that resource sharing remains at the account level, maintaining clear boundaries and simplifying access management for your End User Messaging infrastructure.
Sharing Account vs. Consuming Account:
The sharing account (or owner account) is the AWS account that owns the resources and creates the resource share.
When a principal (such as an AWS account) is granted access to a resource share, it becomes a consuming account. It can use the shared resources according to the permissions granted and pays for its own usage of those resources, not for the resources themselves. For example: The consuming account pays for the volume of SMS sent by a shared number but the sharing account pays for any fees associated with owning that actual number.
AWS Organizations Integration: While you can share resources with individual AWS accounts, the most powerful way to use AWS RAM is in conjunction with AWS Organizations. This service allows you to centrally manage and govern multiple AWS accounts under a single umbrella. When you enable sharing within your organization, you can share resources with all accounts in the organization, or with specific Organizational Units (OUs), seamlessly and without needing to send and accept individual invitations. This sharing is only possible between accounts that reside in the same AWS Region.
Managed Permissions: AWS RAM uses managed permissions to control access.
AWS managed permissions are predefined permission sets created and maintained by AWS for common use cases. For AWS End User Messaging, the key permission is AWSRAMDefaultPermissionSmsVoice, which allows consumers to use the resources for sending messages but not for deleting or modifying them.
Customer managed permissions can be created for more granular control over shared resources.
Resource-Based Policies: Behind the scenes, AWS RAM works by creating and managing resource-based policies for you. These policies are what actually grant the consuming accounts access to the shared resources.
To better illustrate these sharing models, the following diagrams show how a Sharing Account can share its AWS End User Messaging resources using different strategies:
Diagram 1: Direct Account-to-Account Sharing:
Diagram 2: Sharing with an Entire AWS Organization:
Diagram 3: Sharing with a Specific Organizational Unit (OU):
Prerequisites and Setup
For the following walkthrough, we will demonstrate how to configure the setup for Diagram 1: Direct Account-to-Account Sharing. However, the steps for managing and using the resource share are similar for all three scenarios. Before you begin, ensure your environment is set up correctly.
Note for AWS Organizations Users: When your account is managed by AWS Organizations, you can take advantage of that to share resources more easily. With or without Organizations, a user can share with individual accounts. However, if your account is in an organization, then you can share with individual accounts, or with all accounts in the organization or in an OU without having to enumerate each account.
If you plan to share resources using AWS Organizations (as shown in Diagram 2 or Diagram 3), you must complete the following prerequisite steps from your organization’s management account before creating a resource share:
1. Enable all features in your organization:
aws organizations enable-all-features
2. Enable resource sharing with AWS RAM: This creates the necessary service-linked role.
aws ram enable-sharing-with-aws-organization
1. Required IAM Permissions
The IAM user or role performing these actions needs permissions for both AWS RAM and AWS End User Messaging. The following policy grants the necessary permissions to manage resource shares.
Note on Least Privilege: This policy follows the security best practice of granting least privilege. The first statement scopes modification permissions to only AWS RAM resource shares. The second statement grants permissions for discovery actions (like Describe* and List*) and the ram:CreateResourceShare action, which require "Resource": "*" as they do not operate on a specific, pre-existing resource.
2. Regionality Requirement
Important Reminder: resource sharing with AWS RAM is a regional feature. You can only share resources with accounts within the same AWS Region where those resources are located.
For example, a resource in us-east-1 can only be shared with other accounts in us-east-1, regardless of where those accounts operate other resources. Ensure that the resources you intend to share and the accounts that you anticipate sharing with are each considering the same Region for this process.
Creating and Managing Resource Shares (Sharing Account Actions)
This section provides a step-by-step guide to sharing your resources using the AWS CLI. We will walk through creating a resource share, associating and disassociating resources, and checking the status of your shares.
Step 1: Create an Empty Resource Share
First, create the resource share. Think of this as an empty container. You will associate principals (the consuming accounts) and resources (the phone numbers, etc.) with this share.
In the command below, we will create a share named EUM-Shared-Resources for an external account.
# Create a resource share and grant default End User Messaging permissions # Replace 123456789012 with the consuming account's ID
aws ram create-resource-share \
    --name "EUM-Shared-Resources" \
    --principals "123456789012" \
    --permission-arns "arn:aws:ram::aws:permission/AWSRAMDefaultPermissionSmsVoice" \
    --allow-external-principals \
    --region us-east-1
--principals: Specify one or more AWS account IDs.
--allow-external-principals: This flag is required when sharing with accounts that are not part of your AWS Organization.
Expected Response: A successful command returns a JSON object describing the new resource share. Note that allowExternalPrincipals is now true.
Replace ‘region‘, ‘account-id‘, and the specific resource IDs with your actual values.
Step 2: Associate Resources with the Share
Now that you have your “container,” you can add resources to it. The associate-resource-share command links one or more of your End User Messaging resources to the share you just created, making them available to the principals.
# Define the ARN of the resource share from the previous step
RESOURCE_SHARE_ARN="arn:aws:ram:us-east-1:111122223333:resource-share/a1b2c3d4-5678-90ab-cdef-111111111111"

# Associate a phone number and a pool with the share # Replace the resource-arns with your actual resource ARNs
aws ram associate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns \
        "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
        "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --region us-east-1
Expected Response: A successful association returns a JSON object confirming the association and showing its status. The status will initially be ASSOCIATING and will transition to ASSOCIATED once complete.
Note: The association process is asynchronous. We’ll show you how to verify the completion status in the next step using the get-resource-shares and list-resources commands. It’s important to confirm the status has changed to ASSOCIATED before attempting to use the shared resources.
Step 3: Verify the Status and contents of the Share
Before making changes, it’s good practice to verify what’s in the share. Use get-resource-shares to check the status and list-resources to see the contents. This process helps ensure that all intended resources are properly associated and accessible to the principals you’ve designated.
# Verify the association status is ASSOCIATED
aws ram get-resource-shares \
    --resource-owner SELF \
    --name "EUM-Shared-Resources" \
    --association-status ASSOCIATED \
    --region us-east-1
Expected Response: If the command returns no results, wait a few moments and try again. The association process is typically quick but can sometimes take up to a few minutes.
Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.
Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.
# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1
Review the output carefully to ensure all intended resources are listed. If any resources are missing, you may need to reassociate them using the associate-resource-share command.
# List the ARNs of all resources currently in the share
aws ram list-resources \
    --resource-owner SELF \
    --resource-share-arns "$RESOURCE_SHARE_ARN" \
    --region us-east-1
Expected Response (list-resources): This command will return a list of JSON objects, each representing a resource in the share.
Step 4: Disassociate Specific Resources from the Share
To stop sharing a specific resource, you use the disassociate-resource-share command. You must provide the ARN of the resource you wish to remove. This gives you granular control, allowing you to remove one resource while continuing to share others.
# Disassociate only the phone number from the share
aws ram disassociate-resource-share \
    --resource-share-arn "$RESOURCE_SHARE_ARN" \
    --resource-arns "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --region us-east-1
Expected Response: The response will be nearly identical to the associate response, confirming the disassociation request. The status will be DISASSOCIATING.
Once resources are shared, users in the consuming accounts can discover and use them for sending messages.
Step 1: Discovering Shared Resources
From a consuming account, you can list resources that have been shared with you by using the --filters parameter in the describe-* commands.
Note: Shared resources are discoverable via the AWS CLI and SDKs but will not appear in the AWS Management Console of the consuming account. This is expected behavior, as the resources are owned by the sharing account.
# List phone numbers shared with your account
aws pinpoint-sms-voice-v2 describe-phone-numbers \
    --filters Name=shared-with-me,Values=true \
    --region us-east-1
# List sender IDs shared with your account
aws pinpoint-sms-voice-v2 describe-sender-ids \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List pools shared with your account
aws pinpoint-sms-voice-v2 describe-pools \
--filters Name=shared-with-me,Values=true \
--region us-east-1

# List shared opt-out lists with region specification
aws pinpoint-sms-voice-v2 describe-opt-out-lists \
--filters Name=shared-with-me,Values=true \
--region us-east-1
Expected Response: The command returns a JSON object listing the shared resources, including their ARNs, which you will need for sending messages.
Important: When using shared resources, consuming accounts must specify the full ARN of the shared resource in API calls. This differs from resource owners, who can use either the resource ID, ARN, or the number directly. You can specify the ARN of an individual phone number or a pool as the origination-identity.
# Send an SMS using a shared Phone Number ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4" \
    --message-body "Hello from a shared number!" \
    --region us-east-1

# Send an SMS using a shared Pool ARN (consuming account MUST use ARN)
aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+12065550199" \
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:pool/pool-b2c3d4e5" \
    --message-body "Hello from a shared pool!" \
    --region us-east-1
Expected Response: A successful send-text-message call will return a MessageId, which confirms that the service has accepted the message for delivery.
Once a message is sent, understanding its delivery status is crucial for ensuring your communications are effective. AWS End User Messaging provides several mechanisms for tracking message delivery, giving you a multi-layered approach to reporting.
Delivery Receipts (DLRs):
For traditional, carrier-provided Delivery Receipts (DLRs), which can sometimes take up to 72 hours to be returned, you must configure an event destination. This is the most common method for confirming that a message has reached the recipient’s handset, and is achieved through a Configuration Set.
For shared resources:
The configuration set must be created and managed in the sharing account.
The consuming accountmust then reference the ARN of the configuration set when sending messages.
# Example for consuming account
aws pinpoint-sms-voice-v2 send-text-message
    --destination-phone-number "+12065550199"
    --origination-identity "arn:aws:sms-voice:us-east-1:111122223333:phone-number/phonenumber-a1b2c3d4"
    --message-body "Hello from a shared number!"
    --configuration-set-name "arn:aws:sms-voice:us-east-1:111122223333:configuration-set/MyConfigSet"
    --region us-east-1
For more immediate, application-driven insights, you can use the Message Feedback feature. This allows you to programmatically mark messages as “delivered” based on a user’s action, such as using a one-time password (OTP) or clicking a link in the message. This provides a real-time confirmation loop that is independent of carrier DLRs.
Amazon CloudWatch:
To monitor these events at scale, you can stream them to Amazon CloudWatch Logs to track key performance indicators like the number of messages sent and delivered, and to set up alerts based on your specific business needs.
To set up comprehensive reporting:
Configure an event destination for DLRs and detailed status events.
Set up CloudWatch dashboards and alerts for ongoing monitoring.
This multi-layered approach provides both immediate feedback and long-term delivery insights, allowing you to optimize your messaging strategy and quickly identify potential delivery issues.
Troubleshooting Common Issues
Permission Denied Errors: If a consuming account cannot access a shared resource, verify that the consuming account’s IAM policies include the necessary permissions. Here’s an example policy:
Resource Not Visible: Remember that shared resources do not appear in the consuming account’s AWS Management Console. If the describe-* commands with the shared-with-me filter return no results, ensure the resource share status is ACTIVE in the sharing account.
If sharing via AWS Organizations, confirm the consuming account is correctly placed in the specified OU. You can find more information on managing OUs in the AWS Organizations User Guide.
CLI Command Fails: If a command fails with a “not found” or “invalid parameter” error, it is often due to an incorrect ARN. Double-check that the ARNs for resources, principals, and the resource share itself are correct. A Permission Denied error, on the other hand, points to an IAM policy issue..
Best Practices and Considerations
Security: Always follow the principle of least privilege. Use AWS managed permissions like AWSRAMDefaultPermissionSmsVoice where possible and create customer-managed permissions only for specific, granular requirements.
Cost: The sharing account is billed for provisioning the resources (e.g., the monthly cost of a phone number). Consuming accounts are billed for their usage of those shared resources (e.g., the cost per message sent). There are no additional costs for using AWS RAM.
Throughput and Quotas: Resource throughput quotas (e.g., messages per second) are shared along with the resource. High volume sending from multiple consuming accounts using the same shared number or pool, could collectively hit the service quota, which may result in throttling. Plan your usage accordingly or request quota increases if necessary.
Conclusion
This guide has equipped you to centralize your AWS End User Messaging resources using AWS Resource Access Manager. By implementing this strategy, you can directly address the common challenges of a multi-account environment: maintaining consistent branding with shared Sender IDs, ensuring comprehensive compliance with centralized opt-out lists, and reducing operational overhead by managing resources in one place.
We have walked through the entire lifecycle, from the initial prerequisites in AWS Organizations and IAM, to the step-by-step CLI commands for creating shares, associating resources, and enabling consuming accounts to use them. By applying these techniques and keeping the best practices for security and throughput in mind, you are now able to build a more efficient, secure, and scalable communication platform across your entire AWS ecosystem.
AWS Summit season starts this week! These free events are now rolling out worldwide, bringing our cloud computing community together to connect, collaborate, and learn. Whether you prefer joining us online or in-person, these gatherings offer valuable opportunities to expand your AWS knowledge. I will be attending the Summit in Paris this week, the biggest cloud conference in France, and the London Summit at the end of the month. We will have a small podcast recording studio where I will interview French and British customers to produce new episodes for the AWS Developers Podcast and le podcast AWS en .
Register today!
But for now, let’s look at last week’s new announcements.
Last week’s launches At KubeCon London, we introduced the EKS Community Add-Ons Catalog, making it simpler for Kubernetes users to enhance their Amazon EKS clusters with powerful open-source tools. This catalog streamlines the installation of essential add-ons like metrics-server, kube-state-metrics, prometheus-node-exporter, cert-manager, and external-dns. By integrating these community-driven add-ons directly into the EKS console and AWS command line interface (AWS CLI), customers can reduce operational complexity and accelerate deployment while maintaining flexibility and security. This launch reflects AWS’s commitment to the Kubernetes community, providing seamless access to trusted open-source solutions without the overhead of manual installation and maintenance.
Amazon Q Developer now integrates with Amazon OpenSearch Service to enhance operational analytics by enabling natural language exploration and AI-assisted data visualization. This integration simplifies the process of querying and visualizing operational data, reducing the learning curve associated with traditional query languages and tools. During incident responses, Amazon Q Developer offers contextual summaries and insights directly within the alerts interface, facilitating quicker analysis and resolution. This advancement allows engineers to focus more on innovation by streamlining troubleshooting processes and improving monitoring infrastructure.
Amazon SES has introduced support for email attachments in its v2 APIs, enabling users to include files like PDFs and images directly in their emails without manually constructing MIME messages. This enhancement simplifies the process of sending rich email content and reduces implementation complexity. Amazon Simple Email Service (Amazon SES) supports attachments in all AWS Regions where the service is available.
Other AWS events Check your calendar and sign up for upcoming AWS events.
AWS GenAI Lofts are collaborative spaces and immersive experiences that showcase AWS expertise in cloud computing and AI. They provide startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you and don’t forget to register.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
This post is written by Heeki Park, Principal Solutions Architect
Amazon API Gateway is introducing custom domain name support for private REST API endpoints. Customers choose private REST API endpoints when they want endpoints that are only callable from within their Amazon VPC. Custom domain names are simpler and more intuitive URLs that you can use with your applications and were previously only supported with public REST API endpoints. Now you can use custom domain names to map to private REST APIs and share those custom domain names across accounts using AWS Resource Access Manager (AWS RAM).
Overview of API Gateway connectivity
When considering network connectivity with API Gateway, two aspects are important to keep in mind: the integration type and the connectivity type. The following diagram shows examples of those considerations.
Figure 1: Overall architecture
The first aspect is the distinction between frontend integrations and backend integrations. Frontend integrations are how API clients like mobile devices, web browsers, or client applications connect to the API endpoint. Backend integrations are the API services to which your API Gateway endpoint proxies requests, like applications running on Amazon Elastic Compute Cloud (EC2) instances, Amazon Elastic Kubernetes Service (EKS) or Amazon Elastic Container Service (ECS) containers, or as AWS Lambda functions. The second aspect is whether that connectivity is via the public internet or via your private VPC.
Calling private REST API endpoints
In order to send requests to a private REST API endpoint, clients must operate within a VPC that is configured with a VPC endpoint. Once a VPC endpoint is configured, a client has three different options within the VPC for connecting to the API endpoint, depending on how the VPC and the VPC endpoint are configured.
If the VPC endpoint has private DNS enabled, the client can send requests to the standard endpoint URL: https://{api-id}.execute-api.{region}.amazonaws.com/{stage}. These requests resolve to the VPC endpoint, which then get routed to the appropriate API Gateway endpoint.
Figure 2: VPC endpoint configured with private DNS names enabled
Alternatively, if the VPC endpoint has private DNS disabled, the client can send requests to the VPC endpoint URL: https://{vpce-id}.execute-api.{region}.amazonaws.com/{stage}. One of the following headers also needs to be sent along with that request.
Finally, if the VPC endpoint has private DNS disabled and the private REST API endpoint is associated with the VPC endpoint, the client can send requests to the following URL: https://{api-id}-{vpce-id}.execute-api.{region}.amazonaws.com/{stage}. To associate a VPC endpoint with a private API, the following property configures that association.
You can see that configuration in the console, as follows.
Figure 3: Optional VPC endpoint configuration with private REST API endpoints
To simplify access to your private REST API endpoints, you can now also configure custom domain names, which functions as a stable vanity URL for your private APIs.
Implementing custom domain names for private endpoints
Before setting up a custom domain name for your private REST API endpoints, a VPC endpoint for API Gateway, an AWS Certificate Manager (ACM) certificate, an Amazon Route 53 private hosted zone, and one or more private REST API endpoints need to be configured.
Once those pre-requisites are set up, a custom domain name can be setup with the following steps:
In the API provider account, create a custom domain name and base path mapping.
In the provider account, use AWS RAM to create a resource share for the custom domain name. In the consumer account, accept the resource share request. This step is only required if the provider and consumer are in different AWS accounts.
In the consumer account, associate the custom domain name to a VPC endpoint.
In the consumer account, create a Route 53 alias to map the custom domain to the VPC endpoint.
Figure 4: Components for configuring a custom domain name
Step 1: Creating a private custom domain name
When configuring a custom domain name, two policies are used to manage permissions to the private custom domain name resource. Management policies specify which principals are allowed to associate a private custom domain name to a VPC endpoint. Resource-based policies specify which API consumers are allowed to invoke your private custom domain name.
Figure 5: Creating a private custom domain name
This is an example CloudFormation definition for a private custom domain name.
In this example, the management policy specifies that the account 123456789012 is allowed to associate a private custom domain name with a VPC endpoint. The resource-based policy then denies any request that does not come from a particular VPC endpoint and only allows invoke requests that come from that same account 123456789012.
The private custom domain name then needs to be mapped to a private REST API.
In this example, the BasePath is set to app1. If the Stage is set as dev, then the private endpoint can be accessed via https://api.internal.example.com/app1/dev. The domain id is the identifier for the private custom domain name.
Note that with public custom domain names, the domain name has to be unique in the region, since they are resolved publicly. With private custom domain names, since they are resolved within a VPC, a private custom domain name with the same name can be created in different accounts. The private custom domain name is then resolved to the VPC endpoint in that account’s VPC.
Step 2: Sharing the private custom domain name using AWS RAM
In order for API consumers to access the private custom domain name from another account, the custom domain name needs to be shared with the consumer accounts using RAM. If the API provider and API consumer are in the same account, this step with RAM can be skipped.
Figure 6: Sharing the private custom domain name
The following CloudFormation definition creates a resource share in the provider account.
The allowed Principals for the resource share specifies the consumer account ids. The ResourceArns specify the ARN of the private custom domain name.
In the consumer account, an administrator receives a notification to accept the resource share. This request must be accepted to allow the consumer account to see the private custom domain name. This handshake acts as a mutual agreement between the accounts to allow the private custom domain name to be exposed from the provider account to the consumer account. If the provider and consumer accounts are in the same AWS Organization, the share is automatically accepted on behalf of consumers.
Step 3: Associating the private custom domain name to a VPC endpoint
The private custom domain name is now visible in the consumer account. Next, associate the private custom domain name with a VPC endpoint in the consumer account and in the VPC where the client applications reside.
Figure 7: Associating the private custom domain name to a VPC endpoint
The AccessAssociationSource is the VPC endpoint id, and the DomainNameArn is the same ARN that is used in the RAM resource share.
Step 4: Creating a Route 53 alias for the custom domain name
The final step before being able to test the custom domain name in the consumer account is setting up a Route 53 alias. That alias is configured in a private hosted zone that is associated with the VPC where the VPC endpoint and client applications reside. The alias resolves the fully qualified domain name (FQDN) to the VPC endpoint DNS name.
Figure 8: Creating a Route 53 alias
The following CloudFormation definition creates that alias.
The ResourceRecords point to the FQDN of the VPC endpoint to which our private custom domain name is associated. Once this alias is created, your client applications can test if it can successfully send requests to the private custom domain name.
Optional: Cleaning up the resources
If you’ve configured a test environment with these resources, you can clean up the deployment by following the steps in reverse order.
In the consumer account, delete the Route 53 alias.
In the consumer account, delete the association.
In both the consumer and provider account, remove the RAM resource share.
In the provider account, delete the custom domain name and base path mapping.
Conclusion
In this post, you learned about how clients can connect to private REST API endpoints with API Gateway. With custom domain names, your applications connect to stable URLs that can forward requests to many different private API backends. Furthermore, your application teams can deploy resources in separate line of business AWS accounts and access the private custom domain name as a central shared resource, using AWS RAM resource sharing. This allows your application teams to build secure, private API applications and expose them to API consumers securely and across multiple AWS accounts.
For more details, refer to the API Gateway documentation and check out patterns with API Gateway on Serverless Land.
It’s been an interesting week full of AWS news as usual, but also full of vibrant faces filling up the rooms in a variety of events happening this month.
Let’s start by covering some of the releases that have caught my attention this week.
Oracle Database@AWS has been announced as part of a strategic partnership between Amazon Web Services (AWS) and Oracle. This offering allows customers to access Oracle Autonomous Database and Oracle Exadata Database Service directly within AWS simplifying cloud migration for enterprise workloads. Key features include zero-ETL integration between Oracle and AWS services for real-time data analysis, enhanced security, and optimized performance for hybrid cloud environments. This collaboration addresses the growing demand for multi-cloud flexibility and efficiency. It will be available in preview later in the year with broader availability in 2025 as it expands to new Regions.
Amazon OpenSearch Service now supports version 2.15, featuring improvements in search performance, query optimization, and AI-powered application capabilities. Key updates include radial search for vector space queries, optimizations for neural sparse and hybrid search, and the ability to enable vector and hybrid search on existing indexes. Additionally, it also introduces new features like a toxicity detection guardrail and an ML inference processor for enriching ingest pipelines. Read this guide to see how you can upgrade your Amazon OpenSearch Service domain.
So simple yet so good These releases are simple in nature, but have a big impact.
AWS Resource Access Manager (RAM) now supports AWS PrivateLink – With this release, you can now securely share resources across AWS accounts with private connectivity, without exposing traffic to the public internet. This integration allows for more secure and streamlined access to shared services via VPC endpoints, improving network security and simplifying resource sharing across organizations.
AWS Network Firewall now supports AWS PrivateLink – another security quick-win, you can now securely access and manage Network Firewall resources without exposing traffic to the public internet.
AWS IAM Identity Center now enables users to customize their experience – You can set the language and visual mode preferences, including dark mode for improved readability and reduced eye strain. This update supports 12 different languages and enables users to adjust their settings for a more personalized experience when accessing AWS resources through the portal.
Others Amazon EventBridge Pipes now supports customer managed KMS keys – Amazon EventBridge Pipes now supports customer-managed keys for server-side encryption. This update allows customers to use their own AWS Key Management Service (KMS) keys to encrypt data when transferring between sources and targets, offering more control and security over sensitive event data. The feature enhances security for point-to-point integrations without the need for custom integration code. See instructions on how to configure this in the updated documentation.
Amazon SageMaker introduces sticky session routing for inference – This allows requests from the same client to be directed to the same model instance for the duration of a session improving consistency and reducing latency, particularly in real-time inference scenarios like chatbots or recommendation systems, where session-based interactions are crucial. Read about how to configure it in this documentation guide.
Events The AWS GenAI Lofts continue to pop up around the world! This week, developers in San Francisco had the opportunity to attend two very exciting events at the AWS Gen AI Loft in San Francisco including the “Generative AI on AWS” meetup last Tuesday, featuring discussions about extended reality, future AI tools, and more. Then things got playful on Thursday with the demonstration of an Amazon Bedrock-powered MineCraft bot and AI video game battles! If you’re around San Francisco before October 19th make sure to check out the schedule to see the list of events that you can join.
Make sure to check out the AWS GenAI Loft in Sao Paulo, Brazil, which opened recently, and the AWS GenAI Loft in London, which opens September 30th. You can already start registering for events before they fill up including one called “The future of development” that offers a whole day of targeted learning for developers to help them accelerate their skills.
Our AWS communities have also been very busy throwing incredible events! I was privileged to be a speaker at AWS Community Day Belfast where I got to finally meet all of the organizers of this amazing thriving community in Northern Ireland. If you haven’t been to a community day, I really recommend you check them out! You are sure to leave energized by the dedication and passion from communities leaders like Matt Coulter, Kristi Perreault, Matthew Wilson, Chloe McAteer, and their community members – not to mention the smiles all around. 🙂
Certifications If you’ve been postponing taking an AWS certification exam, now is the perfect time! Register free for the AWS Certified: Associate Challenge before December 12, 2024 and get a 50% discount voucher to take any of the following exams: AWS Certified Solutions Architect – Associate, AWS Certified Developer – Associate, AWS Certified SysOps Administrator – Associate, or AWS Certified Data Engineer – Associate. My colleague Jenna Seybold has posted a collection of study material for each exam; check it out if you’re interested.
Also, don’t forget that the brand new AWS Certified AI Practitioner exam is now available. It is in beta stage, but you can already take it. If you pass it before February 15, 2025, you get an Early Adopter badge to add to your collection.
Analytics are vital to the success of a contact center. Having insights into each touchpoint of the customer experience allows you to accurately measure performance and adapt to shifting business demands. While you can find common metrics in the Amazon Connect console, sometimes you need to have more details and custom requirements for reporting based on the unique needs of your business.
Starting today, the Amazon Connect analytics data lake is generally available. As announced last year as preview, this new capability helps you to eliminate the need to build and maintain complex data pipelines. Amazon Connect data lake is zero-ETL capable, so no extract, transform, or load (ETL) is needed.
Here’s a quick look at the Amazon Connect analytics data lake:
Improving your customer experience with Amazon Connect Amazon Connect analytics data lake helps you to unify disparate data sources, including customer contact records and agent activity, into a single location. By having your data in a centralized location, you now have access to analyze contact center performance and gain insights while reducing the costs associated with implementing complex data pipelines.
With Amazon Connect analytics data lake, you can access and analyze contact center data, such as contact trace records and Amazon Connect Contact Lens data. This provides you the flexibility to prepare and analyze data with Amazon Athena and use the business intelligence (BI) tools of your choice, such as, Amazon QuickSight and Tableau.
Get started with the Amazon Connect analytics data lake To get started with the Amazon Connect analytics data lake, you’ll first need to have an Amazon Connect instance setup. You can follow the steps in the Create an Amazon Connect instance page to create a new Amazon Connect instance. Because I’ve already created my Amazon Connect instance, I will go straight to showing you how you can get started with Amazon Connect analytics data lake.
First, I navigate to the Amazon Connect console and select my instance.
Then, on the next page, I can set up my analytics data lake by navigating to Analytics tools and selecting Add data share.
This brings up a pop-up dialog, and I first need to define the target AWS account ID. With this option, I can set up a centralized account to receive all data from Amazon Connect instances running in multiple accounts. Then, under Data types, I can select the types I need to share with the target AWS account. To learn more about the data types that you can share in the Amazon Connect analytics data lake, please visit Associate tables for Analytics data lake.
Once it’s done, I can see the list of all the target AWS account IDs with which I have shared all the data types.
Besides using the AWS Management Console, I can also use the AWS Command Line Interface (AWS CLI) to associate my tables with the analytics data lake. The following is a sample command:
Next, I need to approve (or reject) the request in the AWS Resource Access Manager (RAM) console in the target account. RAM is a service to help you securely share resources across AWS accounts. I navigate to AWS RAM and select Resource shares in the Shared with me section.
Then, I select the resource and select Accept resource share.
At this stage, I can access shared resources from Amazon Connect. Now, I can start creating linked tables from shared tables in AWS Lake Formation. In the Lake Formation console, I navigate to the Tables page and select Create table.
I need to create a Resource link to a shared table. Then, I fill in the details and select the available Database and the Shared table’s region.
Then, when I select Shared table, it will list all the available shared tables that I can access.
Once I select the shared table, it will automatically populate Shared table’s database and Shared table’s owner ID. Once I’m happy with the configuration, I select Create.
To run some queries for the data, I go to the Amazon Athena console.The following is an example of a query that I ran:
With this configuration, I have access to certain Amazon Connect data types. I can even visualize the data by integrating with Amazon QuickSight. The following screenshot show some visuals in the Amazon QuickSight dashboard with data from Amazon Connect.
Customer voice During the preview period, we heard lots of feedback from our customers about Amazon Connect analytics data lake. Here’s what our customer say:
Joulica is an analytics platform supporting insights for software like Amazon Connect and Salesforce. Tony McCormack, founder and CEO of Joulica, said, “Our core business is providing real-time and historical contact center analytics to Amazon Connect customers of all sizes. In the past, we frequently had to set up complex data pipelines, and so we are excited about using Amazon Connect analytics data lake to simplify the process of delivering actionable intelligence to our shared customers.”
Things you need to know
Pricing — Amazon Connect analytics data lake is available for you to use up to 2 years of data without any additional charges in Amazon Connect. You only need to pay for any services you use to interact with the data.
Availability — Amazon Connect analytics data lake is generally available in the following AWS Regions: US East (N. Virginia), US West (Oregon), Africa (Cape Town), Asia Pacific (Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), and Europe (Frankfurt, London)
Learn more — For more information, please visit Analytics data lake documentation page.
You can use AWS Resource Access Manager (AWS RAM) to securely, simply, and consistently share supported resource types within your organization or organizational units (OUs) and across AWS accounts. This means you can provision your resources once and use AWS RAM to share them with accounts. With AWS RAM, the accounts that receive the shared resources can list those resources alongside the resources they own.
When you share your resources by using AWS RAM, you can specify the actions that an account can perform and the access conditions on the shared resource. AWS RAM provides AWS managed permissions, which are created and maintained by AWS and which grant permissions for common customer scenarios. Now, you can further tailor resource access by authoring and applying fine-grained customer managed permissions in AWS RAM. A customer managed permission is a managed permission that you create to precisely specify who can do what under which conditions for the resource types included in your resource share.
This blog post walks you through how to use customer managed permissions to tailor your resource access to meet your business and security needs. Customer managed permissions help you follow the best practice of least privilege for your resources that are shared using AWS RAM.
Many AWS customers share infrastructure services to accounts in an organization from a centralized infrastructure OU. The networking account in the infrastructure OU follows the best practice of least privilege and grants only the permissions that accounts receiving these resources, such as development accounts, require to perform a specific task. The solution in this post demonstrates how you can share an Amazon Virtual Private Cloud (Amazon VPC) IP Address Manager (IPAM) pool with the accounts in a Development OU. IPAM makes it simpler for you to plan, track, and monitor IP addresses for your AWS workloads.
You’ll use a networking account that owns an IPAM pool to share the pool with the accounts in a Development OU. You’ll do this by creating a resource share and a customer managed permission through AWS RAM. In this example, shown in Figure 1, both the networking account and the Development OU are in the same organization. The accounts in the Development OU only need the permissions that are required to allocate a classless inter-domain routing (CIDR) range and not to view the IPAM pool details. You’ll further refine access to the shared IPAM pool so that only AWS Identity and Access Management (IAM) users or roles tagged with team = networking can perform actions on the IPAM pool that’s shared using AWS RAM.
Figure 1: Multi-account diagram for sharing your IPAM pool from a networking account in the Infrastructure OU to accounts in the Development OU
Prerequisites
For this walkthrough, you must have the following prerequisites:
An AWS account (the networking account) with an IPAM pool already provisioned. For this example, create an IPAM pool in a networking account named ipam-vpc-pool-use1-dev. Because you share resources across accounts in the same AWS Region using AWS RAM, provision the IPAM pool in the same Region where your development accounts will access the pool.
An AWS OU with the associated development accounts to share the IPAM pool with. In this example, these accounts are in your Development OU.
An IAM role or user with permissions to perform IPAM and AWS RAM operations in the networking account and the development accounts.
Share your IPAM pool with your Development OU with least privilege permissions
In this section, you share an IPAM pool from your networking account to the accounts in your Development OU and grant least-privilege permissions. To do that, you create a resource share that contains your IPAM pool, your customer managed permission for the IPAM pool, and the OU principal you want to share the IPAM pool with. A resource share contains resources you want to share, the principals you want to share the resources with, and the managed permissions that grant resource access to the account receiving the resources. You can add the IPAM pool to an existing resource share, or you can create a new resource share. Depending on your workflow, you can start creating a resource share either in the Amazon VPC IPAM or in the AWS RAM console.
To initiate a new resource share from the Amazon VPC IPAM console
Next, specify the resource share details, including the name, the resource type, and the specific resource you want to share. Note that the steps of the resource share creation process are located on the left side of the AWS RAM console.
To specify the resource share details
For Name, enter ipam-shared-dev-pool.
For Select resource type, choose IPAM pools.
For Resources, select the Amazon Resource Name (ARN) of the IPAM pool you want to share from a list of the IPAM pool ARNs you own.
Choose Next.
Figure 3: Specify the resources to share in your resource share
Configure customer managed permissions
In this example, the accounts in the Development OU need the permissions required to allocate a CIDR range, but not the permissions to view the IPAM pool details. The existing AWS managed permission grants both read and write permissions. Therefore, you need to create a customer managed permission to refine the resource access permissions for your accounts in the Development OU. With a customer managed permission, you can select and tailor the actions that the development accounts can perform on the IPAM pool, such as write-only actions.
In this section, you create a customer managed permission, configure the managed permission name, select the resource type, and choose the actions that are allowed with the shared resource.
To create and author a customer managed permission
On the Associate managed permissions page, choose Create customer managed permission. This will bring up a new browser tab with a Create a customer managed permission page.
On the Create a customer managed permission page, enter my-ipam-cmp for the Customer managed permission name.
Confirm the Resource type as ec2:IpamPool.
On the Visual editor tab of the Policy template section, select the Write checkbox only. This will automatically check all the available write actions.
Choose Create customer managed permission.
Figure 4: Create a customer managed permission with only write actions
Now that you’ve created your customer managed permission, you must associate it to your resource share.
To associate your customer managed permission
Go back to the previous Associate managed permissions page. This is most likely located in a separate browser tab.
Choose the refresh icon .
Select my-ipam-cmp from the dropdown menu.
Review the policy template, and then choose Next.
Next, select the IAM roles, IAM users, AWS accounts, AWS OUs, or organization you want to share your IPAM pool with. In this example, you share the IPAM pool with an OU in your account.
To grant access to principals
On the Grant access to principals page, select Allow sharing only with your organization.
For Select principal type, choose Organizational unit (OU).
Enter the Development OU’s ID.
Select Add, and then choose Next.
Choose Create resource share to complete creation of your resource share.
Figure 5: Grant access to principals in your resource share
Verify the customer managed permissions
Now let’s verify that the customer managed permission is working as expected. In this section, you verify that the development account cannot view the details of the IPAM pool and that you can use that same account to create a VPC with the IPAM pool.
To verify that an account in your Development OU can’t view the IPAM pool details
Select ipam-shared-dev-pool. You won’t be able to view the IPAM pool details.
To verify that an account in your Development OU can create a new VPC with the IPAM pool
Sign in to the AWS Management Console as an account in your Development OU. For Services, select VPC console.
On the VPC dashboard, choose Create VPC.
On the Create VPC page, select VPC only.
For name, enter my-dev-vpc.
Select IPAM-allocated IPv4 CIDR block.
Choose the ARN of the IPAM pool that’s shared with your development account.
For Netmask, select /24 256 IPs.
Choose Create VPC. You’ve successfully created a VPC with the IPAM pool shared with your account in your Development OU.
Figure 6: Create a VPC
Update customer managed permissions
You can create a new version of your customer managed permission to rescope and update the access granularity of your resources that are shared using AWS RAM. For example, you can add a condition in your customer managed permissions so that only IAM users or roles tagged with a particular principal tag can access and perform the actions allowed on resources shared using AWS RAM. If you need to update your customer managed permission — for example, after testing or as your business and security needs evolve — you can create and save a new version of the same customer managed permission rather than creating an entirely new customer management permission. For example, you might want to adjust your access configurations to read-only actions for your development accounts and to rescope to read-write actions for your testing accounts. The new version of the permission won’t apply automatically to your existing resource shares, and you must explicitly apply it to those shares for it to take effect.
To create a version of your customer managed permission
In the left navigation pane, choose Managed permissions library.
For Filter by text, enter my-ipam-cmp andselect my-ipam-cmp. You can also select the Any type dropdown menu and then select Customer managed to narrow the list of managed permissions to only your customer managed permissions.
On the my-ipam-cmp page, choose Create version.
You can make the customer managed permission more fine-grained by adding a condition. On the Create a customer managed permission for my-ipam-cmp page, under the Policy template section, choose JSON editor.
Add a condition with aws:PrincipalTag that allows only the users or roles tagged with team = networking to access the shared IPAM pool.
Choose Create version. This new version will be automatically set as the default version of your customer managed permission. As a result, new resource shares that use the customer managed permission will use the new version.
Figure 7: Update your customer managed permissions and add a condition statement with aws:PrincipalTag
Note: Now that you have the new version of your customer managed permission, you must explicitly apply it to your existing resource shares for it to take effect.
To apply the new version of the customer managed permission to existing resource shares
On the my-ipam-cmp page, under the Managed permission versions, select Version 1.
Choose the Associated resource shares tab.
Find ipam-shared-dev-pool and next to the current version number, select Update to default version. This will update your ipam-shared-dev-pool resource share with the new version of your my-ipam-cmp customer managed permission.
To verify your updated customer managed permission, see the Verify the customer managed permissions section earlier in this post. Make sure that you sign in with an IAM role or user tagged with team = networking, and then repeat the steps of that section to verify your updated customer managed permission. If you use an IAM role or user that is not tagged with team = networking, you won’t be able to allocate a CIDR from the IPAM pool and you won’t be able to create the VPC.
Cleanup
To remove the resources created by the preceding example:
Delete the resource share from the AWS RAM console.
Deprovision the CIDR from the IPAM pool.
Delete the IPAM pool you created.
Summary
This blog post presented an example of using customer managed permissions in AWS RAM. AWS RAM brings simplicity, consistency, and confidence when sharing your resources across accounts. In the example, you used AWS RAM to share an IPAM pool to accounts in a Development OU, configured fine-grained resource access controls, and followed the best practice of least privilege by granting only the permissions required for the accounts in the Development OU to perform a specific task with the shared IPAM pool. In the example, you also created a new version of your customer managed permission to rescope the access granularity of your resources that are shared using AWS RAM.
In Part 1 of this two-part series, we shared an overview of some of the most important 2021 Amazon Web Services (AWS) Security service and feature launches. In this follow-up, we’ll dive deep into additional launches that are important for security professionals to be aware of and understand across all AWS services. There have already been plenty in the first half of 2022, so we’ll highlight those soon, as well.
AWS Identity
You can use AWS Identity Services to build Zero Trust architectures, help secure your environments with a robust data perimeter, and work toward the security best practice of granting least privilege. In 2021, AWS expanded the identity source options, AWS Region availability, and support for AWS services. There is also added visibility and power in the permission management system. New features offer new integrations, additional policy checks, and secure resource sharing across AWS accounts.
AWS Single Sign-On
For identity management, AWS Single Sign-On (AWS SSO) is where you create, or connect, your workforce identities in AWS once and manage access centrally across your AWS accounts in AWS Organizations. In 2021, AWS SSO announced new integrations for JumpCloud and CyberArk users. This adds to the list of providers that you can use to connect your users and groups, which also includes Microsoft Active Directory Domain Services, Okta Universal Directory, Azure AD, OneLogin, and Ping Identity.
For access management, there have been a range of feature launches with AWS Identity and Access Management (IAM) that have added up to more power and visibility in the permissions management system. Here are some key examples.
IAM made it simpler to relate a user’s IAM role activity to their corporate identity. By setting the new source identity attribute, which persists through role assumption chains and gets logged in AWS CloudTrail, you can find out who is responsible for actions that IAM roles performed.
IAM added support for policy conditions, to help manage permissions for AWS services that access your resources. This important feature launch of service principal conditions helps you to distinguish between API calls being made on your behalf by a service principal, and those being made by a principal inside your account. You can choose to allow or deny the calls depending on your needs. As a security professional, you might find this especially useful in conjunction with the aws:CalledVia condition key, which allows you to scope permissions down to specify that this account principal can only call this API if they are calling it using a particular AWS service that’s acting on their behalf. For example, your account principal can’t generally access a particular Amazon Simple Storage Service (Amazon S3) bucket, but if they are accessing it by using Amazon Athena, they can do so. These conditions can also be used in service control policies (SCPs) to give account principals broader scope across an account, organizational unit, or organization; they need not be added to individual principal policies or resource policies.
Another very handy new IAM feature launch is additional information about the reason for an access denied error message. With this additional information, you can now see which of the relevant access control policies (for example, IAM, resource, SCP, or VPC endpoint) was the cause of the denial. As of now, this new IAM feature is supported by more than 50% of all AWS services in the AWS SDK and AWS Command Line Interface, and a fast-growing number in the AWS Management Console. We will continue to add support for this capability across services, as well as add more features that are designed to make the journey to least privilege simpler.
IAM Access Analyzer also launched the ability to generate fine-grained policies based on analyzing past AWS CloudTrail activity. This feature provides a great new capability for DevOps teams or central security teams to scope down policies to just the permissions needed, making it simpler to implement least privilege permissions. IAM Access Analyzer launched further enhancements to expand policy checks, and the ability to generate a sample least-privilege policy from past activity was expanded beyond the account level to include an analysis of principal behavior within the entire organization by analyzing log activity stored in AWS CloudTrail.
AWS Resource Access Manager
AWS Resource Access Manager (AWS RAM) helps you securely share your resources across unrelated AWS accounts within your organization or organizational units (OUs) in AWS Organizations. Now you can also share your resources with IAM roles and IAM users for supported resource types. This update enables more granular access using managed permissions that you can use to define access to shared resources. In addition to the default managed permission defined for each shareable resource type, you now have more flexibility to choose which permissions to grant to whom for resource types that support additional managed permissions. Additionally, AWS RAM added support for global resource types, enabling you to provision a global resource once, and share that resource across your accounts. A global resource is one that can be used in multiple AWS Regions; the first example of a global resource is found in AWS Cloud WAN, currently in preview as of this publication. AWS RAM helps you more securely share an AWS Cloud WAN core network, which is a managed network containing AWS and on-premises networks. With AWS RAM global resource sharing, you can use the Cloud WAN core network to centrally operate a unified global network across Regions and accounts.
AWS Directory Service
AWS Directory Service for Microsoft Active Directory, also known as AWS Managed Microsoft Active Directory (AD), was updated to automatically provide domain controller and directory utilization metrics in Amazon CloudWatch for new and existing directories. Analyzing these utilization metrics helps you quantify your average and peak load times to identify the need for additional domain controllers. With this, you can define the number of domain controllers to meet your performance, resilience, and cost requirements.
Amazon Cognito
Amazon Cognitoidentity pools (federated identities) was updated to enable you to use attributes from social and corporate identity providers to make access control decisions and simplify permissions management in AWS resources. In Amazon Cognito, you can choose predefined attribute-tag mappings, or you can create custom mappings using the attributes from social and corporate providers’ access and ID tokens, or SAML assertions. You can then reference the tags in an IAM permissions policy to implement attribute-based access control (ABAC) and manage access to your AWS resources. Amazon Cognito also launched a new console experience for user pools and now supports targeted sign out through refresh token revocation.
Governance, control, and logging services
There were a number of important releases in 2021 in the areas of governance, control, and logging services.
This approach provides a powerful new middle ground between the older security models of prevention (which provide developers only an access denied message, and often can’t distinguish between an acceptable and an unacceptable use of the same API) and a detect and react model (when undesired states have already gone live). The Cfn-Guard 2.0 model gives builders the freedom to build with IaC, while allowing central teams to have the ability to reject infrastructure configurations or changes that don’t conform to central policies—and to do so with completely custom error messages that invite dialog between the builder team and the central team, in case the rule is unnuanced and needs to be refined, or if a specific exception needs to be created.
For example, a builder team might be allowed to provision and attach an internet gateway to a VPC, but the team can do this only if the routes to the internet gateway are limited to a certain pre-defined set of CIDR ranges, such as the public addresses of the organization’s branch offices. It’s not possible to write an IAM policy that takes into account the CIDR values of a VPC route table update, but you can write a Cfn-Guard 2.0 rule that allows the creation and use of an internet gateway, but only with a defined and limited set of IP addresses.
AWS Systems Manager Incident Manager
An important launch that security professionals should know about is AWS Systems Manager Incident Manager. Incident Manager provides a number of powerful capabilities for managing incidents of any kind, including operational and availability issues but also security issues. With Incident Manager, you can automatically take action when a critical issue is detected by an Amazon CloudWatch alarm or Amazon EventBridge event. Incident Manager runs pre-configured response plans to engage responders by using SMS and phone calls, can enable chat commands and notifications using AWS Chatbot, and runs automation workflows with AWS Systems Manager Automation runbooks. The Incident Manager console integrates with AWS Systems Manager OpsCenter to help you track incidents and post-incident action items from a central place that also synchronizes with third-party management tools such as Jira Service Desk and ServiceNow. Incident Manager enables cross-account sharing of incidents using AWS RAM, and provides cross-Region replication of incidents to achieve higher availability.
Amazon Simple Storage Service (Amazon S3) is one of the most important services at AWS, and its steady addition of security-related enhancements is always big news. Here are the 2021 highlights.
Access Points aliases
Amazon S3 introduced a new feature, Amazon S3 Access Points aliases. With Amazon S3 Access Points aliases, you can make the access points backwards-compatible with a large amount of existing code that is programmed to interact with S3 buckets rather than access points.
To understand the importance of this launch, we have to go back to 2019 to the launch of Amazon S3 Access Points. Access points are a powerful mechanism for managing S3 bucket access. They provide a great simplification for managing and controlling access to shared datasets in S3 buckets. You can create up to 1,000 access points per Region within each of your AWS accounts. Although bucket access policies remain fully enforced, you can delegate access control from the bucket to its access points, allowing for distributed and granular control. Each access point enforces a customizable policy that can be managed by a particular workgroup, while also avoiding the problem of bucket policies needing to grow beyond their maximum size. Finally, you can also bind an access point to a particular VPC for its lifetime, to prevent access directly from the internet.
With the 2021 launch of Access Points aliases, Amazon S3 now generates a unique DNS name, or alias, for each access point. The Access Points aliases look and acts just like an S3 bucket to existing code. This means that you don’t need to make changes to older code to use Amazon S3 Access Points; just substitute an Access Points aliases wherever you previously used a bucket name. As a security team, it’s important to know that this flexible and powerful administrative feature is backwards-compatible and can be treated as a drop-in replacement in your various code bases that use Amazon S3 but haven’t been updated to use access point APIs. In addition, using Access Points aliases adds a number of powerful security-related controls, such as permanent binding of S3 access to a particular VPC.
S3 Bucket Keys were launched at the end of 2020, another great launch that security professionals should know about, so here is an overview in case you missed it. S3 Bucket Keys are data keys generated by AWS KMS to provide another layer of envelope encryption in which the outer layer (the S3 Bucket Key) is cached by S3 for a short period of time. This extra key layer increases performance and reduces the cost of requests to AWS KMS. It achieves this by decreasing the request traffic from Amazon S3 to AWS KMS from a one-to-one model—one request to AWS KMS for each object written to or read from Amazon S3—to a one-to-many model using the cached S3 Bucket Key. The S3 Bucket Key is never stored persistently in an unencrypted state outside AWS KMS, and so Amazon S3 ultimately must always return to AWS KMS to encrypt and decrypt the S3 Bucket Key, and thus, the data. As a result, you still retain control of the key hierarchy and resulting encrypted data through AWS KMS, and are still able to audit Amazon S3 returning periodically to AWS KMS to refresh the S3 Bucket Keys, as logged in CloudTrail.
Returning to our review of 2021, S3 Bucket Keys gained the ability to use Amazon S3 Inventory and Amazon S3 Batch Operations automatically to migrate objects from the higher cost, slightly lower-performance SSE-KMS model to the lower-cost, higher-performance S3 Bucket Keys model.
To understand this launch, we need to go in time to the origins of Amazon S3, which is one of the oldest services in AWS, created even before IAM was launched in 2011. In those pre-IAM days, a storage system like Amazon S3 needed to have some kind of access control model, so Amazon S3 invented its own: Amazon S3 access control lists (ACLs). Using ACLs, you could add access permissions down to the object level, but only with regard to access by other AWS account principals (the only kind of identity that was available at the time), or public access (read-only or read-write) to an object. And in this model, objects were always owned by the creator of the object, not the bucket owner.
After IAM was introduced, Amazon S3 added the bucket policy feature, a type of resource policy that provides the rich features of IAM, including full support for all IAM principals (users and roles), time-of-day conditions, source IP conditions, ability to require encryption, and more. For many years, Amazon S3 access decisions have been made by combining IAM policy permissions and ACL permissions, which has served customers well. But the object-writer-is-owner issue has often caused friction. The good news for security professionals has been that a deny by either type of access control type overrides an allow by the other, so there were no security issues with this bi-modal approach. The challenge was that it could be administratively difficult to manage both resource policies—which exist at the bucket and access point level—and ownership and ACLs—which exist at the object level. Ownership and ACLs might potentially impact the behavior of only a handful of objects, in a bucket full of millions or billions of objects.
With the features released in 2021, Amazon S3 has removed these points of friction, and now provides the features needed to reduce ownership issues and to make IAM-based policies the only access control system for a specified bucket. The first step came in 2020 with the ability to make object ownership track bucket ownership, regardless of writer. But that feature applied only to newly-written objects. The final step is the 2021 launch we’re highlighting here: the ability to disable at the bucket level the evaluation of all existing ACLs—including ownership and permissions—effectively nullifying all object ACLs. From this point forward, you have the mechanisms you need to govern Amazon S3 access with a combination of S3 bucket policies, S3 access point policies, and (within the same account) IAM principal policies, without worrying about legacy models of ACLs and per-object ownership.
Additional database and storage service features
AWS Backup Vault Lock
AWS Backup added an important new additional layer for backup protection with the availability of AWS Backup Vault Lock. A vault lock feature in AWS is the ability to configure a storage policy such that even the most powerful AWS principals (such as an account or Org root principal) can only delete data if the deletion conforms to the preset data retention policy. Even if the credentials of a powerful administrator are compromised, the data stored in the vault remains safe. Vault lock features are extremely valuable in guarding against a wide range of security and resiliency risks (including accidental deletion), notably in an era when ransomware represents a rising threat to data.
ACM Private CA achieved FedRAMP authorization for six additional AWS Regions in the US.
Additional certificate customization now allows administrators to tailor the contents of certificates for new use cases, such as identity and smart card certificates; or to securely add information to certificates instead of relying only on the information present in the certificate request.
Additional capabilities were added for sharing CAs across accounts by using AWS RAM to help administrators issue fully-customized certificates, or revoke them, from a shared CA.
Integration with Kubernetes provides a more secure certificate authority solution for Kubernetes containers.
Online Certificate Status Protocol (OCSP) provides a fully-managed solution for notifying endpoints that certificates have been revoked, without the need for you to manage or operate infrastructure yourself.
Network and application protection
We saw a lot of enhancements in network and application protection in 2021 that will help you to enforce fine-grained security policies at important network control points across your organization. The services and new capabilities offer flexible solutions for inspecting and filtering traffic to help prevent unauthorized resource access.
AWS WAF
AWS WAF launched AWS WAF Bot Control, which gives you visibility and control over common and pervasive bots that consume excess resources, skew metrics, cause downtime, or perform other undesired activities. The Bot Control managed rule group helps you monitor, block, or rate-limit pervasive bots, such as scrapers, scanners, and crawlers. You can also allow common bots that you consider acceptable, such as status monitors and search engines. AWS WAF also added support for custom responses, managed rule group versioning, in-line regular expressions, and Captcha. The Captcha feature has been popular with customers, removing another small example of “undifferentiated work” for customers.
AWS Shield Advanced
AWS Shield Advanced now automatically protects web applications by blocking application layer (L7) DDoS events with no manual intervention needed by you or the AWS Shield Response Team (SRT). When you protect your resources with AWS Shield Advanced and enable automatic application layer DDoS mitigation, Shield Advanced identifies patterns associated with L7 DDoS events and isolates this anomalous traffic by automatically creating AWS WAF rules in your web access control lists (ACLs).
Amazon CloudFront
In other edge networking news, Amazon CloudFront added support for response headers policies. This means that you can now add cross-origin resource sharing (CORS), security, and custom headers to HTTP responses returned by your CloudFront distributions. You no longer need to configure your origins or use custom Lambda@Edge or CloudFront Functions to insert these headers.
Following Route 53 Resolver’s much-anticipated launch of DNS logging in 2020, the big news for 2021 was the launch of its DNS Firewall capability. Route 53 Resolver DNS Firewall lets you create “blocklists” for domains you don’t want your VPC resources to communicate with, or you can take a stricter, “walled-garden” approach by creating “allowlists” that permit outbound DNS queries only to domains that you specify. You can also create alerts for when outbound DNS queries match certain firewall rules, allowing you to test your rules before deploying for production traffic. Route 53 Resolver DNS Firewall launched with two managed domain lists—malware domains and botnet command and control domains—enabling you to get started quickly with managed protections against common threats. It also integrated with Firewall Manager (see the following section) for easier centralized administration.
AWS Network Firewall and Firewall Manager
Speaking of AWS Network Firewall and Firewall Manager, 2021 was a big year for both. Network Firewall added support for AWS Managed Rules, which are groups of rules based on threat intelligence data, to enable you to stay up to date on the latest security threats without writing and maintaining your own rules. AWS Network Firewall features a flexible rules engine enabling you to define firewall rules that give you fine-grained control over network traffic. As of the launch in late 2021, you can enable managed domain list rules to block HTTP and HTTPS traffic to domains identified as low-reputation, or that are known or suspected to be associated with malware or botnets. Prior to that, another important launch was new configuration options for rule ordering and default drop, making it simpler to write and process rules to monitor your VPC traffic. Also in 2021, Network Firewall announced a major regional expansion following its initial launch in 2020, and a range of compliance achievements and eligibility including HIPAA, PCI DSS, SOC, and ISO.
Elastic Load Balancing now supports forwarding traffic directly from Network Load Balancer (NLB) to Application Load Balancer (ALB). With this important new integration, you can take advantage of many critical NLB features such as support for AWS PrivateLink and exposing static IP addresses for applications that still require ALB.
The AWS Networking team also made Amazon VPC private NAT gateways available in both AWS GovCloud (US) Regions. The expansion into the AWS GovCloud (US) Regions enables US government agencies and contractors to move more sensitive workloads into the cloud by helping them to address certain regulatory and compliance requirements.
Compute
Security professionals should also be aware of some interesting enhancements in AWS compute services that can help improve their organization’s experience in building and operating a secure environment.
Amazon Elastic Compute Cloud (Amazon EC2) launched the Global View on the console to provide visibility to all your resources across Regions. Global View helps you monitor resource counts, notice abnormalities sooner, and find stray resources. A few days into 2022, another simple but extremely useful EC2 launch was the new ability to obtain instance tags from the Instance Metadata Service (IMDS). Many customers run code on Amazon EC2 that needs to introspect about the EC2 tags associated with the instance and then change its behavior depending on the content of the tags. Prior to this launch, you had to associate an EC2 role and call the EC2 API to get this information. That required access to API endpoints, either through a NAT gateway or a VPC endpoint for Amazon EC2. Now, that information can be obtained directly from the IMDS, greatly simplifying a common use case.
Amazon EC2 launched sharing of Amazon Machine Images (AMIs) with AWS Organizations and Organizational Units (OUs). Previously, you could share AMIs only with specific AWS account IDs. To share AMIs within AWS Organizations, you had to explicitly manage sharing of AMIs on an account-by-account basis, as they were added to or removed from AWS Organizations. With this new feature, you no longer have to update your AMI permissions because of organizational changes. AMI sharing is automatically synchronized when organizational changes occur. This feature greatly helps both security professionals and governance teams to centrally manage and govern AMIs as you grow and scale your AWS accounts. As previously noted, this feature was also added to EC2 Image Builder. Finally, Amazon Data Lifecycle Manager, the tool that manages all your EBS volumes and AMIs in a policy-driven way, now supports automatic deprecation of AMIs. As a security professional, you will find this helpful as you can set a timeline on your AMIs so that, if the AMIs haven’t been updated for a specified period of time, they will no longer be considered valid or usable by development teams.
Looking ahead
In 2022, AWS continues to deliver experiences that meet administrators where they govern, developers where they code, and applications where they run. We will continue to summarize important launches in future blog posts. If you’re interested in learning more about AWS services, join us for AWS re:Inforce, the AWS conference focused on cloud security, identity, privacy, and compliance. AWS re:Inforce 2022 will take place July 26–27 in Boston, MA. Registration is now open. Register now with discount code SALxUsxEFCw to get $150 off your full conference pass to AWS re:Inforce. For a limited time only and while supplies last. We look forward to seeing you there!
To stay up to date on the latest product and feature launches and security use cases, be sure to read the What’s New with AWS announcements (or subscribe to the RSS feed) and the AWS Security Blog.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Many organizations need to connect their on-premises data centers, remote sites, and cloud resources. A hybrid connectivity approach connects these different environments. Customers with a hybrid connectivity network need additional infrastructure and configuration for private DNS resolution to work consistently across the network. It is a challenge to build this type of DNS infrastructure for a multi-account environment. However, there are several options available to address this problem with AWS. Automating DNS infrastructure using Route 53 Resolver endpoints covers how to use Resolver endpoints or private hosted zones to manage your DNS infrastructure.
Control Tower Customizations with Service Catalog solution overview
The solution uses the Customizations for Control Tower framework and AWS Service Catalog to provision the DNS resources across a multi-account setup. The Service Catalog Portfolio created by the solution consists of three Amazon Route 53 products: Outbound DNS product, Inbound DNS product, and Private DNS. Sharing this portfolio with the organization makes the products available to both existing and future accounts in your organization. Users who are given access to AWS Service Catalog can choose to provision these three Route 53 products in a self-service or a programmatic manner.
Outbound DNS product. This solution creates inbound and outbound Route 53 resolver endpoints in a Networking Hub account. Deploying the solution creates a set of Route 53 resolver rules in the same account. These resolver rules are then shared with the organization via AWS Resource Access Manager (RAM). Amazon VPCs in spoke accounts are then associated with the shared resolver rules by the Service Catalog Outbound DNS product.
Inbound DNS product. A private hosted zone is created in the Networking Hub account to provide on-premises resolution of Amazon VPC IP addresses. A DNS forwarder for the cloud namespace is required to be configured by the customer for the on-premises DNS servers. This must point to the IP addresses of the Route 53 Inbound Resolver endpoints. Appropriate resource records (such as a CNAME record to a spoke account resource like an Elastic Load Balancer or a private hosted zone) are added. Once this has been done, the spoke accounts can launch the Inbound DNS Service Catalog product. This activates an AWS Lambda function in the hub account to authorize the spoke VPC to be associated to the Hub account private hosted zone. This should permit a client from on-premises to resolve the IP address of resources in your VPCs in AWS.
Private DNS product. For private hosted zones in the spoke accounts, the corresponding Service Catalog product enables each spoke account to deploy a private hosted zone. The DNS name is a subdomain of the parent domain for your organization. For example, if the parent domain is cloud.example.com, one of the spoke account domains could be called spoke3.cloud.example.com. The product uses the local VPC ID (spoke account) and the Network Hub VPC ID. It also uses the Region for the Network Hub VPC that is associated to this private hosted zone. You provide the ARN of the Amazon SNS topic from the Networking Hub account. This creates an association of the Hub VPC to the newly created private hosted zone, which allows the spoke account to notify the Networking Hub account.
The notification from the spoke account is performed via a custom resource that is a part of the private hosted zone product. Processing of the notification in the Networking Hub account to create the VPC association is performed by a Lambda function in the Networking Hub account. We also record each authorization-association within Amazon DynamoDB tables in the Networking Hub account. One table is mapping the account ID with private hosted zone IDs and domain name, and the second table is mapping hosted zone IDs with VPC IDs.
The following diagram (Figure 1) shows the solution architecture:
Figure 1. A Service Catalog based DNS architecture setup with Route 53 Outbound DNS product, Inbound DNS product, and Route 53 Private DNS product
Prerequisites
Network connectivity between the Network Hub VPC and the on-premises DNS servers is in place. Connectivity can be either VPN or AWS Direct Connect.
6. Under the same route53 directory, create another sub-directory called parameters. Place the updated parameter json file from previous step under this folder.
7. Edit the manifest.yaml file in the root of your CfCT CodeCommit repository to include the Route 53 resource, manifest.yml is provided as a reference. Update the Region values in this example to the Region of your Control Tower. Also update the deployment target account name to the equivalent Networking Hub account within your AWS Organization.
8. Create and push a commit for the changes made to the CfCT solution to your CodeCommit repository.
9. Finally, navigate to AWS CodePipeline in the AWS Management Console to monitor the progress. Validate the deployment of resources via CloudFormation StackSets is complete to the target Networking Hub account.
Phase 2: Setup user access, and provision Route 53 products using AWS Service Catalog in spoke accounts
In this section, we walk through how users can vend products from the shared AWS Service Catalog Portfolio using a self-service model. The following steps will walk you through setting up user access and provision products:
1. Sign in to AWS Management Console of the spoke account in which you want to deploy the Route 53 product.
2. Navigate to the AWS Service Catalog service, and choose Portfolios.
3. On the Imported tab, choose your portfolio as shown in Figure 2.
Figure 2. Imported DNS portfolio (spoke account)
4. Choose the Groups, roles, and users pane and add the IAM role, user, or group that you want to use to launch the product.
5. In the left navigation pane, choose Products as shown in Figure 3.
6. On the Products page, choose either of the three products, and then choose Launch Product.
Figure 3. DNS portfolio products (Inbound DNS, Outbound DNS, and Private DNS products)
7. On the Launch Product page, enter a name for your provisioned product, and provide the product parameters:
Outbound DNS product:
ChildDomainNameResolverRuleId: Rule ID for the Shared Route 53 Resolver rule for child domains.
OnPremDomainResolverRuleID: Rule ID for the Shared Route 53 Resolver rule for on-premises DNS domain.
LocalVPCID: Enter the VPC ID, which the Route 53 Resolver rules are to be associated with (for example: vpc-12345).
Inbound DNS product:
NetworkingHubPrivateHostedZoneDomain: Domain of the private hosted zone in the hub account.
LocalVPCID: Enter the ID of the VPC from the account and Region where you are provisioning this product (for example: vpc-12345).
SNSAuthorizationTopicArn: Enter ARN of the SNS topic belonging to the Networking Hub account.
Private DNS product:
DomainName: the FQDN for the private hosted zone (for example: account1.parent.internal.com).
LocalVPCId: Enter the ID of the VPC from the account and Region where you are provisioning this product.
AdditionalVPCIds: Enter the ID of the VPC from the Network Hub account that you want to associate to your private hosted zone.
AdditionalAccountIds: Provide the account IDs of the VPCs mentioned in AdditionalVPCIds.
NetworkingHubAccountId: Account ID of the Networking Hub account
SNSAssociationTopicArn: Enter ARN of the SNS topic belonging to the Networking Hub account.
8. Select Next and Launch Product.
Validation of Control Tower Customizations with Service Catalog solution
For the Outbound DNS product:
Validate the successful DNS infrastructure provisioning. To do this, navigate to Route 53 service in the AWS Management Console. Under the Rules section, select the rule you provided when provisioning the product.
Under that Rule, confirm that spoke VPC is associated to this rule.
For further validation, launch an Amazon EC2 instance in one of the spoke accounts. Resolve the DNS name of a record present in the on-premises DNS domain using the dig utility.
For the Inbound DNS product:
In the Networking Hub account, navigate to the Route 53 service in the AWS Management Console. Select the private hosted zone created here for inbound access from on-premises. Verify the presence of resource records and the VPCs to ensure spoke account VPCs are associated.
For further validation, from a client on-premises, resolve the DNS name of one of your AWS specific domains, using the dig utility, for example.
For the Route 53 private hosted zone (Private DNS) product:
Navigate to the hosted zone in the Route 53 AWS Management Console.
Expand the details of this hosted zone. You should see the VPCs (VPC IDs that were provided as inputs) associated during product provisioning.
For further validation, create a DNS A record in the Route 53 private hosted zone of one of the spoke accounts.
Spin up an EC2 instance in the VPC of another spoke account.
Resolve the DNS name of the record created in the previous step using the dig utility.
Additionally, the details of each VPC and private hosted zone association is maintained within DynamoDB tables in the Networking Hub account
Cleanup steps
All the resources deployed through CloudFormation templates should be deleted after successful testing and validation to avoid any unwanted costs.
Remove the changes made to the CfCT repo to remove the references to the Route 53 folder in the manifest.yaml and the route53 folder. Then commit and push the changes to prevent future re-deployment.
Go to the CloudFormation console, identify the stacks appropriately, and delete them.
In spoke accounts, you can shut down the provisioned AWS Service Catalog product(s), which would terminate the corresponding CloudFormation stacks on your behalf.
Note: In a multi account setup, you must navigate through account boundaries and follow the previous steps where products were deployed.
Conclusion
In this post, we showed you how to create a portfolio using AWS Service Catalog. It contains a Route 53 Outbound DNS product, an Inbound DNS product, and a Private DNS product. We described how you can share this portfolio with your AWS Organization. Using this solution, you can provision Route 53 infrastructure in a programmatic, repeatable manner to standardize your DNS infrastructure.
We hope that you’ve found this post informative and we look forward to hearing how you use this feature!
This post is written by Yi-Kang Wang, Senior Hybrid Specialist SA.
AWS Outposts rack is a fully managed service that delivers the same AWS infrastructure, AWS services, APIs, and tools to virtually any on-premises datacenter or co-location space for a truly consistent hybrid experience. AWS Outposts rack is ideal for workloads that require low latency access to on-premises systems, local data processing, data residency, and migration of applications with local system interdependencies. In addition to these benefits, we have started to see many of you need to share Outposts rack resources across business units and projects within your organization. This blog post will discuss how you can share Outposts rack resources by creating computing quotas on Outposts with Amazon Elastic Compute Cloud (Amazon EC2) Capacity Reservations sharing.
In AWS Regions, you can set up and govern a multi-account AWS environment using AWS Organizations and AWS Control Tower. The natural boundaries of accounts provide some built-in security controls, and AWS provides additional governance tooling to help you achieve your goals of managing a secure and scalable cloud environment. And while Outposts can consistently use organizational structures for security purposes, Outposts introduces another layer to consider in designing that structure. When an Outpost is shared within an Organization, the utilization of the purchased capacity also needs to be managed and tracked within the organization. The account that owns the Outpost resource can use AWS Resource Access Manager (RAM) to create resource shares for member accounts within their organization. An Outposts administrator (admin) can share the ability to launch instances on the Outpost itself, access to the local gateways (LGW) route tables, and/or access to customer-owned IPs (CoIP). Once the Outpost capacity is shared, the admin needs a mechanism to control the usage and prevent over utilization by individual accounts. With the introduction of Capacity Reservations on Outposts, we can now set up a mechanism for computing quotas.
Concept of computing quotas on Outposts rack
In the AWS Regions, Capacity Reservations enable you to reserve compute capacity for your Amazon EC2 instances in a specific Availability Zone for any duration you need. On May 24, 2021, Capacity Reservations were enabled for Outposts rack. It supports not only EC2 but Outposts services running over EC2 instances such as Amazon Elastic Kubernetes (EKS), Amazon Elastic Container Service (ECS) and Amazon EMR. The computing power of above services could be covered in your resource planning as well. For example, you’d like to launch an EKS cluster with two self-managed worker nodes for high availability. You can reserve two instances with Capacity Reservations to secure computing power for the requirement.
Here I’ll describe a method for thinking about resource pools that an admin can use to manage resource allocation. I’ll use three resource pools, that I’ve named reservation pool, bulk and attic, to effectively and extensibly manage the Outpost capacity.
A reservation pool is a resource pool reserved for a specified member account. An admin creates a Capacity Reservation to match member account’s need, and shares the Capacity Reservation with the member account through AWS RAM.
A bulk pool is an unreserved resource pool that is used when member accounts run out of compute capacity such as EC2, EKS, or other services using EC2 as underlay. All compute capacity in the bulk pool can be requested to launch until it is exhausted. Compute capacity that is not under a reservation pool belongs to the bulk pool by default.
An attic is a resource pool created to hold the compute capacity that the admin wouldn’t like to share with member accounts. The compute capacity remains in control by admin, and can be released to the bulk pool when needed. Admin creates a Capacity Reservation for the attic and owns the Capacity Reservation.
The following diagram shows how the admin uses Capacity Reservations with AWS RAM to manage computing quotas for two member accounts on an Outpost equipped with twenty-four m5.xlarge. Here, I’m going to break the idea into several pieces to help you understand easily.
There are three Capacity Reservations created by admin. CR #1 reserves eight m5.xlarge for the attic, CR #2 reserves four m5.xlarge instances for account A and CR #3 reserves six m5.xlarge instances for account B.
The admin shares Capacity Reservation CR #2 and CR #3 with account A and B respectively.
Since eighteen m5.xlarge instances are reserved, the remaining compute capacity in the bulk pool will be six m5.xlarge.
Both Account A and B can continue to launch instances exceeding the amount in their Capacity Reservation, by utilizing the instances available to everyone in the bulk pool.
Once the bulk pool is exhausted, account A and B won’t be able to launch extra instances from the bulk pool.
The admin can release more compute capacity from the attic to refill the bulk pool, or directly share more capacity with CR#2 and CR#3. The following diagram demonstrates how it works.
Based on this concept, we realize that compute capacity can be securely and efficiently allocated among multiple AWS accounts. Reservation pools allow every member account to have sufficient resources to meet consistent demand. Making the bulk pool empty indirectly sets the maximum quota of each member account. The attic plays as a provider that is able to release compute capacity into the bulk pool for temporary demand. Here are the major benefits of computing quotas.
Centralized compute capacity management
Reserving minimum compute capacity for consistent demand
Resizable bulk pool for temporary demand
Limiting maximum compute capacity to avoid resource congestion.
Configuration process
To take you through the process of configuring computing quotas in the AWS console, I have simplified the environment like the following architecture. There are four m5.4xlarge instances in total. An admin account holds two of the m5.4xlarge in the attic, and a member account gets the other two m5.4xlarge for the reservation pool, which results in no extra instance in the bulk pool for temporary demand.
Prerequisites
The admin and the member account are within the same AWS Organization.
The Outpost ID, LGW and CoIP have been shared with the member account.
Creating a Capacity Reservation for the member account
Sign in to AWS console of the admin account and navigate to the AWS Outposts page. Select the Outpost ID you want to share with the member account, choose Actions, and then select Create Capacity Reservation. In this case, reserve two m5.4xlarge instances.
In the Reservation details, you can terminate the Capacity Reservation by manually enabling or selecting a specific time. The first option of Instance eligibility will automatically count the number of instances against the Capacity Reservation without specifying a reservation ID. To avoid misconfiguration from member accounts, I suggest you select Any instance with matching details in most use cases.
Sharing the Capacity Reservation through AWS RAM
Go to the RAM page, choose Create resource share under Resource shares page. Search and select the Capacity Reservation you just created for the member account.
Choose a principal that is an AWS ID of the member account.
Creating a Capacity Reservation for attic
Create a Capacity Reservation like step 1 without sharing with anyone. This reservation will just be owned by the admin account. After that, check Capacity Reservations under the EC2 page, and the two Capacity Reservations there, both with availability of two m5.4xlarge instances.
Launching EC2 instances
Log in to the member account, select the Outpost ID the admin shared in step 2 then choose Actions and select Launch instance. Follow AWS Outposts User Guide to launch two m5.4xlarge on the Outpost. When the two instances are in Running state, you can see a Capacity Reservation ID on Details page. In this case, it’s cr-0381467c286b3d900.
So far, the member account has run out of two m5.4xlarge instances that the admin reserved for. If you try to launch the third m5.4xlarge instance, the following failure message will show you there is not enough capacity.
Allocating more compute capacity in bulk pool
Go back to the admin console, select the Capacity Reservation ID of the attic on EC2 page and choose Edit. Modify the value of Quantity from 2 to 1 and choose Save, which means the admin is going to release one more m5.4xlarge instance from the attic to the bulk pool.
Launching more instances from bulk pool
Switch to the member account console, and repeat step 4 but only launch one more m5.4xlarge instance. With the resource release on step 5, the member account successfully gets the third instance. The compute capacity is coming from the bulk pool, so when you check the Details page of the third instance, the Capacity Reservation ID is blank.
Cleaning up
Terminate the three EC2 instances in the member account.
Unshare the Capacity Reservation in RAM and delete it in the admin account.
Unshare the Outpost ID, LGW and CoIP in RAM to get the Outposts resources back to the admin.
Conclusion
In this blog post, the admin can dynamically adjust compute capacity allocation on Outposts rack for purpose-built member accounts with an AWS Organization. The bulk pool offers an option to fulfill flexibility of resource planning among member accounts if the maximum instance need per member account is unpredictable. By contrast, if resource forecast is feasible, the admin can revise both the reservation pool and the attic to set a hard limit per member account without using the bulk pool. In addition, I only showed you how to create a Capacity Reservation of m5.4xlarge for the member account, but in fact an admin can create multiple Capacity Reservations with various instance types or sizes for a member account to customize the reservation pool. Lastly, if you would like to securely share Amazon S3 on Outposts with your member accounts, check out Amazon S3 on Outposts now supports sharing across multiple accounts to get more details.
Many AWS customers use multiple AWS accounts and Regions across different departments and applications within the same company. However, you might deploy services like Amazon QuickSight using a single-account approach to centralize users, data source access, and dashboard management. This post explores how you can use different Amazon Virtual Private Cloud (Amazon VPC) private connectivity features to connect QuickSight to Amazon RDS or Amazon Redshift deployed in a different AWS account or Region.
Prepare the QuickSight environment
To implement any of the options discussed in this post, you need QuickSight with an Enterprise Edition subscription. One of the differences between this edition and the Standard Edition is the ability to connect QuickSight to a VPC—through an Elastic Network Interface (ENI)—and keep network traffic private within the AWS network. In this section, we take you through creating a VPC and enabling a VPC connection for QuickSight. For the rest of this post, you use AWS CloudShell from the AWS Management Console to run AWS Command Line Interface (AWS CLI) commands.
Before you complete the following steps, make sure you have sufficient AWS Identity and Access Management (IAM) privileges associated with your IAM user or role to create VPC endpoints, security groups, route tables, and a VPC peering connection.
If you have Amazon RDS or Amazon Redshift in the same Region and your organization uses cross-account resource sharing for your VPC, you can skip the next steps and go to the section on VPC sharing.
If you already have a VPC and subnet you want to use, you can skip to step 3.
Create a VPC and a subnet in the Region where your QuickSight account is deployed. See the following code:
aws ec2 create-vpc \
    --cidr-block CIDR block different than where redshift and rds are deployed \
    --tag-specifications \
 'ResourceType=vpc,Tags=[{Key=Name,Value=QuicksightVPC}]
Create a subnet where QuickSight can deploy an ENI:
aws ec2 create-subnet \
    --vpc-id ID of the VPC you created above\
    --cidr-block subnet cidr block within your VPC range \
    --tag-specifications \
    'ResourceType=subnet,Tags=[{Key=Name,Value=QuicksightSubnet}]'
Create a security group and allow a self-reference for all TCP traffic from the VPC CIDR range:
aws ec2 create-security-group \
    --group-name QuicksightSG \
    --description "Quicksight security group" \
    --vpc-id ID of the VPC you created above \
    --tag-specifications 'ResourceType=security-group,Tags=[{Key=Name,Value=QuicksightSG}]'
Create a route table and associate it to the subnet you created:
aws ec2 create-route-table \
    --vpc-id ID of the VPC you created above \
    --tag-specifications 'ResourceType=route- \ table,Tags=[{Key=Name,Value=QuicksightRouteTable}]'
aws ec2 associate-route-table \
    --route-table-id id of route table created above \
    --subnet-id subnet id created above
Now you configure QuickSight to create a VPC connection in the subnet you just created.
Sign in to the QuickSight console with administrator privileges.
Choose your profile icon and choose Manage QuickSight.
On the Manage QuickSight console, in the left panel, choose Manage VPC Connections.
Choose Add VPC Connection.
Provide the VPC ID, subnet ID, and security group ID you created earlier.
You can leave DNS resolver endpoints empty unless you have a private DNS deployment in the VPC.
You have now enabled QuickSight to access a subnet in your VPC. The following diagram shows the infrastructure you deployed.
Set up the data source infrastructure
You can choose from multiple possible deployment models when connecting Amazon Redshift or Amazon RDS. In the following sections, we walk you through how you can achieve each solution and when to use each one. For the rest of this post, we refer to Amazon Redshift and Amazon RDS as the data source.
VPC peering
A VPC peering connection is a networking connection between two VPCs that enables you to route traffic between them using private addresses. Instances in either VPC can communicate with each other as if they’re within the same network. This model is suitable for when the two accounts aren’t in the same AWS Organizations organization or Region, or are in the same organization but there is no AWS Transit Gateway attachment to the data source VPC. In this section, we create a network path between the QuickSight VPC and the data source VPC.
Create a VPC peering between the two VPCs. For instructions, see Creating and accepting a VPC peering connection. To use the hostname of the data source, you need to enable the DNS resolution for the peering connection at the requester and accepter of the peering connection. The DNS resolution must also be enabled at bot VPCs for this to work.
Run the following commands to enable the DNS resolution (depending on which account or Region the peering connection is initiated in, you need to run one command in the requester account or Region and the other in the accepter account or Region)
aws ec2 modify-vpc-peering-connection-options \
    --vpc-peering-connection-id your peering connection id \
    --accepter-peering-connection-options \
'{"AllowDnsResolutionFromRemoteVpc":true}'
aws ec2 modify-vpc-peering-connection-options \
    --vpc-peering-connection-id your peering connection id \
    --requester-peering-connection-options \
'{"AllowDnsResolutionFromRemoteVpc":true}'
Update the route tables in both the QuickSight VPC and data source VPC to route network traffic between them:
aws ec2 create-route \
    --route-table-id amazon quicksight subnet route table id\
    --destination-cidr-block data source vpc cidr \
    --vpc-peering-connection-id the id of the peering you created above
aws ec2 create-route \
    --route-table-id data source subnet route table id\
    --destination-cidr-block quicksight vpc cidr \
    --vpc-peering-connection-id the id of the peering you created above
Finally, you update the security groups for both QuickSight and the data source to allow traffic. If both VPCs are in the same Region, you can reference the security group instead of the CIDR of either data source or the QuickSight subnet.
In the QuickSight AWS account, run the following command:
In the data source AWS account, run the following command:
aws ec2 authorize-security-group-ingress \
    --group-id data source security group \
    --ip-permissions \
IpProtocol=tcp,FromPort=0,ToPort=65535,IpRanges=[{CidrIp=quicksight subnet CIDR}]
You have now created and configured a network path between QuickSight and your data source. The following diagram shows the infrastructure you deployed.
You can skip the next sections and proceed to connecting QuickSight to the data source.
AWS Transit Gateway
Transit Gateway connects VPCs through a central hub. It’s usually used in large deployments because it simplifies your network and reduces complex peering relationships. The transit gateway acts as a cloud router—each new connection is only made one time. A deployment model for the VPC of QuickSight with Transit Gateway is suitable when your network or infrastructure team has a policy on limiting VPC peering connections and enforces all new connections between VPCs through the transit gateway.
The Transit Gateway deployment model only works if the two AWS accounts are in the same organization and Region. This method also works if you have two transit gateway in different region that are peered.
Complete the following steps to create a network path between the QuickSight VPC and the data source VPC:
Run the following command to attach the QuickSight VPC to the shared transit gateway:
aws ec2 create-transit-gateway-vpc-attachment \
    --transit-gateway-id transit gateway id \
    --vpc-id quicksight vpc id \
    --subnet-id quicksight subnet id \
    --options {"DnsSupport": "enable"}
Run the following commands to accept the transit gateway attachment you created:
aws ec2 accept-transit-gateway-vpc-attachment \
    --transit-gateway-attachment-id your transit gateway attachment id
Now you need to update the transit gateway attachment with same route table that is used by the data source VPC transit gateway attachment.
Get the route table ID (TransitGatewayRouteTableId) with the following command:
aws ec2 describe-transit-gateway-attachments \
    --transit-gateway-attachment-ids your transit gateway id
Run the following command to attach the route table to the transit gateway attachment of QuickSight:
aws ec2 associate-transit-gateway-route-table \
    --transit-gateway-route-table-id your transit gateway id \
    --transit-gateway-attachment-id your transit gateway attachment id
Lastly, we update the security groups for both QuickSight and the data source to allow traffic.
In the AWS account where QuickSight is deployed, run the following command:
In the AWS account where the data source is deployed, run the following command:
aws ec2 authorize-security-group-ingress \
    --group-id data source security group \
    --ip-permissions \
IpProtocol=tcp,FromPort=0,ToPort=65535,IpRanges=[{CidrIp=quicksight subnet CIDR}]
You have now created and configured a network path between QuickSight and your data source. The following diagram shows the infrastructure you deployed.
You can skip the next sections and proceed to connecting QuickSight to the data source.
AWS PrivateLink
AWS PrivateLink provides private connectivity between VPCs, AWS services, and your on-premises networks. It simplifies your network architecture and makes it easy to connect AWS services across different accounts and VPCs.
You can use AWS PrivateLink as a self-managed endpoint to connect two VPCs or as a managed VPC endpoint for some services like Amazon Redshift. With an Amazon Redshift-managed VPC endpoint, you can privately access your Amazon Redshift data warehouse in your VPC from your client applications in another VPC within the same AWS account or another AWS account.
A self-managed AWS PrivateLink deployment is a solution for cross-account access; however, I don’t discuss it in this post. The solution relies on the IP of the data source ENI, which may change, which causes the AWS PrivateLink endpoint to lose connectivity to the data source, because the AWS PrivateLink Network Load Balancer uses IP-as-a-target to refer to the data source. This results in QuickSight being unable to refresh the dashboards and reports until you update the AWS PrivateLink configuration with the new IP.
The following steps walk you through creating a network path—using an Amazon Redshift managed VPC endpoint—between the QuickSight VPC and the data source VPC. This method only works with the RA3-instance of Amazon Redshift and not the DS2 instances.
Set up an Amazon Redshift-managed VPC endpoint between the Amazon Redshift cluster VPC and QuickSight VPC. For instructions, see Connecting to Amazon Redshift using an interface VPC endpoint. Then you update the security groups for both QuickSight and Amazon Redshift to allow traffic.
In the AWS account where QuickSight is deployed, run the following command:
In the AWS account where the data source is deployed, run the following command:
aws ec2 authorize-security-group-ingress \
    --group-id data source security group \
    --ip-permissions \
IpProtocol=tcp,FromPort=0,ToPort=65535,IpRanges=[{CidrIp=quicksight subnet CIDR}]
You have now created and configured a network path between QuickSight and your Amazon Redshift cluster. The following diagram shows the infrastructure you deployed.
You can skip the next section and proceed to connecting QuickSight to the data source.
VPC sharing
VPC sharing allows multiple AWS accounts to create their application resources, such as Amazon Elastic Compute Cloud (Amazon EC2) or RDS instances, into a shared, centrally managed VPC. In this model, the account that owns the VPC where the data source is deployed (owner) shares one or more subnets with other accounts (participants) that belong to the same organization. After a subnet is shared, the participants can use QuickSight to create the VPC connection in a subnet shared with them. Participants can’t view, modify, or delete resources that belong to other participants or the VPC owner.
This model is the most cost-effective because there’s no underlying cost for VPC peering, Transit Gateway, or AWS PrivateLink. It also simplifies network topologies and reduces the number of VPCs that you create and manage, while using separate accounts for billing and access control for each service used.
The following steps walk you through creating a VPC share and deploying a QuickSight ENI in the VPC to connect to the data source.
Share the data source VPC with the AWS account where QuickSight is deployed. For instructions, see Work with shared VPCs.
You have now created and configured a network path between QuickSight and your data source. The following diagram shows the infrastructure you deployed.
You can now connect QuickSight to the data source.
Connect QuickSight to the data source
Now that you have established the network link and configured both QuickSight and the data source to accept incoming and outgoing network traffic, you set up QuickSight to connect to the data source.
On the QuickSight console, choose Datasets in the navigation pane.
Choose Add a dataset.
Choose your database engine (such as PostgreSQL, MySQL or Redshift Manual connect). Do not choose Amazon RDS or Amazon Redshift auto-discover.
For Connection type, choose the VPC connection you created.
Provide the necessary information about your database server.
Choose Validate connection button to make sure QuickSight can connect to the data source.
Choose Create data source.
Choose the database you want to use and select the table.
You’re now ready to build your dashboards and reports.
Clean up
After following these steps, you should have successfully connected QuickSight to your data source. To avoid incurring any extra charges from the VPC configurations you made and depending on the use case you followed, you should delete the VPC peering, AWS PrivateLink endpoint, or transit gateway attachment.
Conclusion
In this post, we walked through reference access patterns that connect QuickSight to either Amazon RDS or Amazon Redshift running either on a different account, Region, or both. These methods aren’t limited to Amazon RDS or Amazon Redshift; you can use them with any database engine that is self-managed on Amazon EC2 and supported by QuickSight.
The following table summarizes the different deployment models and the preferred way to connect QuickSight to the data source.
Same Region
Different Region
Data Source
Data Source
Amazon Redshift RA3
Amazon RDS or Amazon Redshift DC2
Amazon Redshift RA3
Amazon RDS or Amazon Redshift DC2
Different AWS accounts same AWS organization
Amazon Redshift managed VPC endpoint or VPC sharing
After you set up your various data sources, you can join your data across various sources. You can also use these new data sources to gain further insights from your data by setting up ML Insights in QuickSight and setting graphical representations of your data using QuickSight visuals.
About the author
LotfiMouhib is a Senior Solutions Architect working for the Public Sector team with Amazon Web Services. He helps public sector customers across EMEA realize their ideas, build new services, and innovate for citizens. In his spare time, Lotfi enjoys cycling and running.
This post was co-written by Anandprasanna Gaitonde, AWS Solutions Architect and John Bickle, Senior Technical Account Manager, AWS Enterprise Support
Introduction
Many AWS customers have internal business applications spread over multiple AWS accounts and on-premises to support different business units. In such environments, you may find a consistent view of DNS records and domain names between on-premises and different AWS accounts useful. Route 53 Private Hosted Zones (PHZs) and Resolver endpoints on AWS create an architecture best practice for centralized DNS in hybrid cloud environment. Your business units can use flexibility and autonomy to manage the hosted zones for their applications and support multi-region application environments for disaster recovery (DR) purposes.
This blog presents an architecture that provides a unified view of the DNS while allowing different AWS accounts to manage subdomains. It utilizes PHZs with overlapping namespaces and cross-account multi-region VPC association for PHZs to create an efficient, scalable, and highly available architecture for DNS.
Architecture Overview
You can set up a multi-account environment using services such as AWS Control Tower to host applications and workloads from different business units in separate AWS accounts. However, these applications have to conform to a naming scheme based on organization policies and simpler management of DNS hierarchy. As a best practice, the integration with on-premises DNS is done by configuring Amazon Route 53 Resolver endpoints in a shared networking account. Following is an example of this architecture.
Figure 1 – Architecture Diagram
The customer in this example has on-premises applications under the customer.local domain. Applications hosted in AWS use subdomain delegation to aws.customer.local. The example here shows three applications that belong to three different teams, and those environments are located in their separate AWS accounts to allow for autonomy and flexibility. This architecture pattern follows the option of the “Multi-Account Decentralized” model as described in the whitepaper Hybrid Cloud DNS options for Amazon VPC.
This architecture involves three key components:
1. PHZ configuration: PHZ for the subdomain aws.customer.local is created in the shared Networking account. This is to support centralized management of PHZ for ancillary applications where teams don’t want individual control (Item 1a in Figure). However, for the key business applications, each of the teams or business units creates its own PHZ. For example, app1.aws.customer.local – Application1 in Account A, app2.aws.customer.local – Application2 in Account B, app3.aws.customer.local – Application3 in Account C (Items 1b in Figure). Application1 is a critical business application and has stringent DR requirements. A DR environment of this application is also created in us-west-2.
For a consistent view of DNS and efficient DNS query routing between the AWS accounts and on-premises, best practice is to associate all the PHZs to the Networking Account. PHZs created in Account A, B and C are associated with VPC in Networking Account by using cross-account association of Private Hosted Zones with VPCs. This creates overlapping domains from multiple PHZs for the VPCs of the networking account. It also overlaps with the parent sub-domain PHZ (aws.customer.local) in the Networking account. In such cases where there is two or more PHZ with overlapping namespaces, Route 53 resolver routes traffic based on most specific match as described in the Developer Guide.
2. Route 53 Resolver endpoints for on-premises integration (Item 2 in Figure): The networking account is used to set up the integration with on-premises DNS using Route 53 Resolver endpoints as shown in Resolving DNS queries between VPC and your network. Inbound and Outbound Route 53 Resolver endpoints are created in the VPC in us-east-1 to serve as the integration between on-premises DNS and AWS. The DNS traffic between on-premises to AWS requires an AWS Site2Site VPN connection or AWS Direct Connect connection to carry DNS and application traffic. For each Resolver endpoint, two or more IP addresses can be specified to map to different Availability Zones (AZs). This helps create a highly available architecture.
3. Route 53 Resolver rules (Item 3 in Figure): Forwarding rules are created only in the networking account to route DNS queries for on-premises domains (customer.local) to the on-premises DNS server. AWS Resource Access Manager (RAM) is used to share the rules to accounts A, B and C as mentioned in the section “Sharing forwarding rules with other AWS accounts and using shared rules” in the documentation. Account owners can now associate these shared rules with their VPCs the same way that they associate rules created in their own AWS accounts. If you share the rule with another AWS account, you also indirectly share the outbound endpoint that you specify in the rule as described in the section “Considerations when creating inbound and outbound endpoints” in the documentation. This implies that you use one outbound endpoint in a region to forward DNS queries to your on-premises network from multiple VPCs, even if the VPCs were created in different AWS accounts. Resolver starts to forward DNS queries for the domain name that’s specified in the rule to the outbound endpoint and forward to the on-premises DNS servers. The rules are created in both regions in this architecture.
This architecture provides the following benefits:
Resilient and scalable
Uses the VPC+2 endpoint, local caching and Availability Zone (AZ) isolation
Minimal forwarding hops
Lower cost: optimal use of Resolver endpoints and forwarding rules
In order to handle the DR, here are some other considerations:
For app1.aws.customer.local, the same PHZ is associated with VPC in us-west-2 region. While VPCs are regional, the PHZ is a global construct. The same PHZ is accessible from VPCs in different regions.
Failover routing policy is set up in the PHZ and failover records are created. However, Route 53 health checkers (being outside of the VPC) require a public IP for your applications. As these business applications are internal to the organization, a metric-based health check with Amazon CloudWatch can be configured as mentioned in Configuring failover in a private hosted zone.
Resolver endpoints are created in VPC in another region (us-west-2) in the networking account. This allows on-premises servers to failover to these secondary Resolver inbound endpoints in case the region goes down.
A second set of forwarding rules is created in the networking account, which uses the outbound endpoint in us-west-2. These are shared with Account A and then associated with VPC in us-west-2.
In addition, to have DR across multiple on-premises locations, the on-premises servers should have a secondary backup DNS on-premises as well (not shown in the diagram). This ensures a simple DNS architecture for the DR setup, and seamless failover for applications in case of a region failure.
Considerations
If Application 1 needs to communicate to Application 2, then the PHZ from Account A must be shared with Account B. DNS queries can then be routed efficiently for those VPCs in different accounts.
Create additional IP addresses in a single AZ/subnet for the resolver endpoints, to handle large volumes of DNS traffic.
Hybrid cloud environments can utilize the features of Route 53 Private Hosted Zones such as overlapping namespaces and the ability to perform cross-account and multi-region VPC association. This creates a unified DNS view for your application environments. The architecture allows for scalability and high availability for business applications.
Amazon Web Services (AWS) customers who establish shared infrastructure services in a multi-account environment through AWS Organizations and AWS Resource Access Manager (RAM) may find that the default permissions assigned to the management account are too broad. This may allow organizational accounts to share virtual private clouds (VPCs) with other accounts that shouldn’t have access. Many AWS customers, such as those in regulated industries or who handle sensitive data, may need tighter control of which AWS accounts can share VPCs and which accounts can access shared VPCs.
This blog post describes a mechanism for using service control policies (SCPs) to provide that granular control when you create VPC subnet resource shares within AWS Organizations. These organization policies create a preventative guardrail for controlling which accounts in AWS Organizations can share VPC resources, and with whom. The approach outlined here helps to ensure that your AWS accounts comply with your organization’s access control guidelines for VPC sharing.
A VPC sharing scenario in a multi-account environment
When you set up a multi-account environment in AWS, you can create a good foundation to support your cloud projects by incorporating AWS best practices. AWS Control Tower can automate the implementation of best practices and help your organization achieve its centralized governance and business agility goals. One AWS best practice is to create a shared service network account to consolidate networking components, such as subnets, that can be used by the rest of the organization without duplication of resources and costs. AWS RAM provides the ability to share VPC subnets across accounts. This helps to leverage the implicit routing within a VPC for applications that require a high degree of interconnectivity. VPC subnet sharing across accounts allows individual teams to co-locate their microservice application stacks in a single VPC, and provides several advantages:
Easier administration and management of VPCs in a central network account.
Separation of duties—in other words, network admins retain control over management of VPCs, network access control lists (network ACLs), and security groups, while application teams have permissions to deploy resources and workloads in those VPCs.
High density of Classless Inter-Domain Routing (CIDR) block usage for VPC subnets and avoidance of the problem of CIDR overlap that is encountered with multiple VPCs.
Reuse of network address translation (NAT) gateways, VPC interface endpoints, and avoidance of inter-VPC connectivity costs.
In order to allow for VPC subnets to be shared, you must turn on resource sharing from the management account for your AWS Organizations structure. See Shared VPC prerequisites for more information. This allows sharing of VPC subnets across any accounts within AWS Organizations. However, RAM resource sharing does not provide granular control over VPC shared access.
Let’s consider a customer organization that has set up a multi-account environment with AWS Organizations. The organization consists of segmented accounts and organization units (OUs). The following diagram shows such a multi-OU multi-account environment for a customer who has several teams using the AWS environment for their applications and initiatives.
Figure 1: VPC sharing in a customer’s multi-account AWS environment
The AWS environment is structured as follows:
The Infrastructure OU consists of AWS accounts that contain shared resources for the organization. This OU contains a central network account that contains all the networking resources to be shared with other AWS Organization accounts. Network administrators create a VPC in the networking account with a public and private subnet. This VPC is created for the purpose of sharing the subnets with other teams that need access for their workloads.
The Applications OU consists of AWS accounts that are used by several application teams. These are external and internal application stacks that require a VPC-based infrastructure.
The Data Science OU consists of AWS accounts that are used by teams working on data analytics applications and business intelligence (BI) tools. These applications use serverless data analytics tools for Extract-Transform-Load (ETL) pipelines and big data processing workloads. They have third-party BI tools that need to be hosted in AWS and used by the BI team of the organization for reporting.
Cloud administrators turn on resource sharing in AWS RAM from the management account for their organization. The network administrators operating within the network account create a resource share for the two subnets by using AWS RAM, and share them with the Applications OU so that the application teams can use the shared subnets.
However, this approach opens the door to sharing AWS VPC subnets from any AWS account to any other AWS account as long as the admin users of individual accounts have access to AWS RAM. An example of such unintended or unwanted sharing is when the Application OU account could share a resource with the Data Science OU account, bypassing the centralized network account to satisfy one-off project requests or Proof of Concepts (POCs) that violate the centralized VPC sharing policy.
As a security best practice, cloud administrators should follow the principle of least privilege and use granular controls for VPC sharing. The cloud administrator in this example wants to limit AWS Identity and Access Management (IAM) users with policies that restrict users’ access to AWS RAM to create resource shares. However, this setup can be cumbersome to manage when there are several OUs and numerous AWS accounts. For a more efficient way to have granular control over VPC sharing, you can enable security guardrails by using service control policies (SCPs), as described in the next section. We will walk you through example SCP policies that restrict VPC sharing within AWS Organizations.
Use service control policies to control VPC sharing
In the scenario we described earlier, cloud admins want to allow VPC sharing with the following constraints:
Allow only VPC subnet shares created from a network account
Allow VPC subnet shares to be shared only with certain OUs or AWS accounts
You can achieve these constraints by using the following service control policies.
Both of these service control policies are attached at the root of AWS Organizations, so they are applied to all underlying OUs and accounts. When a network administrator who has logged into the network account tries to create a VPC subnet resource share and associate it with the Application OU, the resource share is successfully created and available to both the Internalapp and Externalapp AWS accounts. However, when the network admin tries to associate the resource share with the DataAnalytics account (which lies outside of the permitted Application OU), the RAMControl2 SCP prevents that action, based on the first condition in the policy statement. The second condition on the RAMControl2 SCP prevents action for specific AWS accounts. In that case, you will see the following error.
Figure 2 Resource share creation is blocked by the SCP
Likewise, when an AWS account administrator of the Externalapp account creates a VPC in that account and tries to share it with the Internalapp account, an error is displayed and the SCP prevents that action. The RAMControl1 SCP prevents the action because it allows only the network account to create and associate resource shares.
Considerations
When you use service control policies within a multi-account structure, it’s important to keep in mind the following considerations:
Customers apply SCPs for several governance and guardrail requirements. The SCPs mentioned here will be evaluated in conjunction with all other SCPs applied at that level in the hierarchy or inherited from above in the hierarchy. See How to use SCPs in AWS Organizations for more information.
AWS strongly recommends that you don’t attach SCPs to the root of your organization without thoroughly testing to ensure that you don’t inadvertently lock users out of key services thereby impacting AWS production environments.
While the example here specifies applying SCPs at the root level, you can take a similar approach if you want to control VPC sharing within a specific OU.
SCPs can be applied to shared resources other than VPC subnets for similar control. To find the complete list of resources that can be specified by using ram: RequestedResourceType, see How AWS RAM works with IAM.
VPC subnets can be shared with AWS accounts and OUs only within an organization. For more information, see the Limitations section in Working with shared VPCs.
Summary
This blog post provides a starting point for learning how to use SCPs to create a granular governance control for VPC sharing. See the IAM conditions keys for AWS RAM and Example SCPs for AWS RAM for more information that can help you implement this preventative guardrail in a way that’s suitable for your AWS environment.
Adding granular governance controls using SCP limits overly permissive sharing and prevents unauthorized resource sharing. Granular control of VPC sharing also helps you follow the AWS security best practice, the principle of least privilege, for access to VPCs. You can take advantage of organization-level SCPs for granular control of resources, which doesn’t require that you turn on resource sharing in AWS Organizations for services such as AWS Transit Gateway or Amazon Route 53 resolver rules.
If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
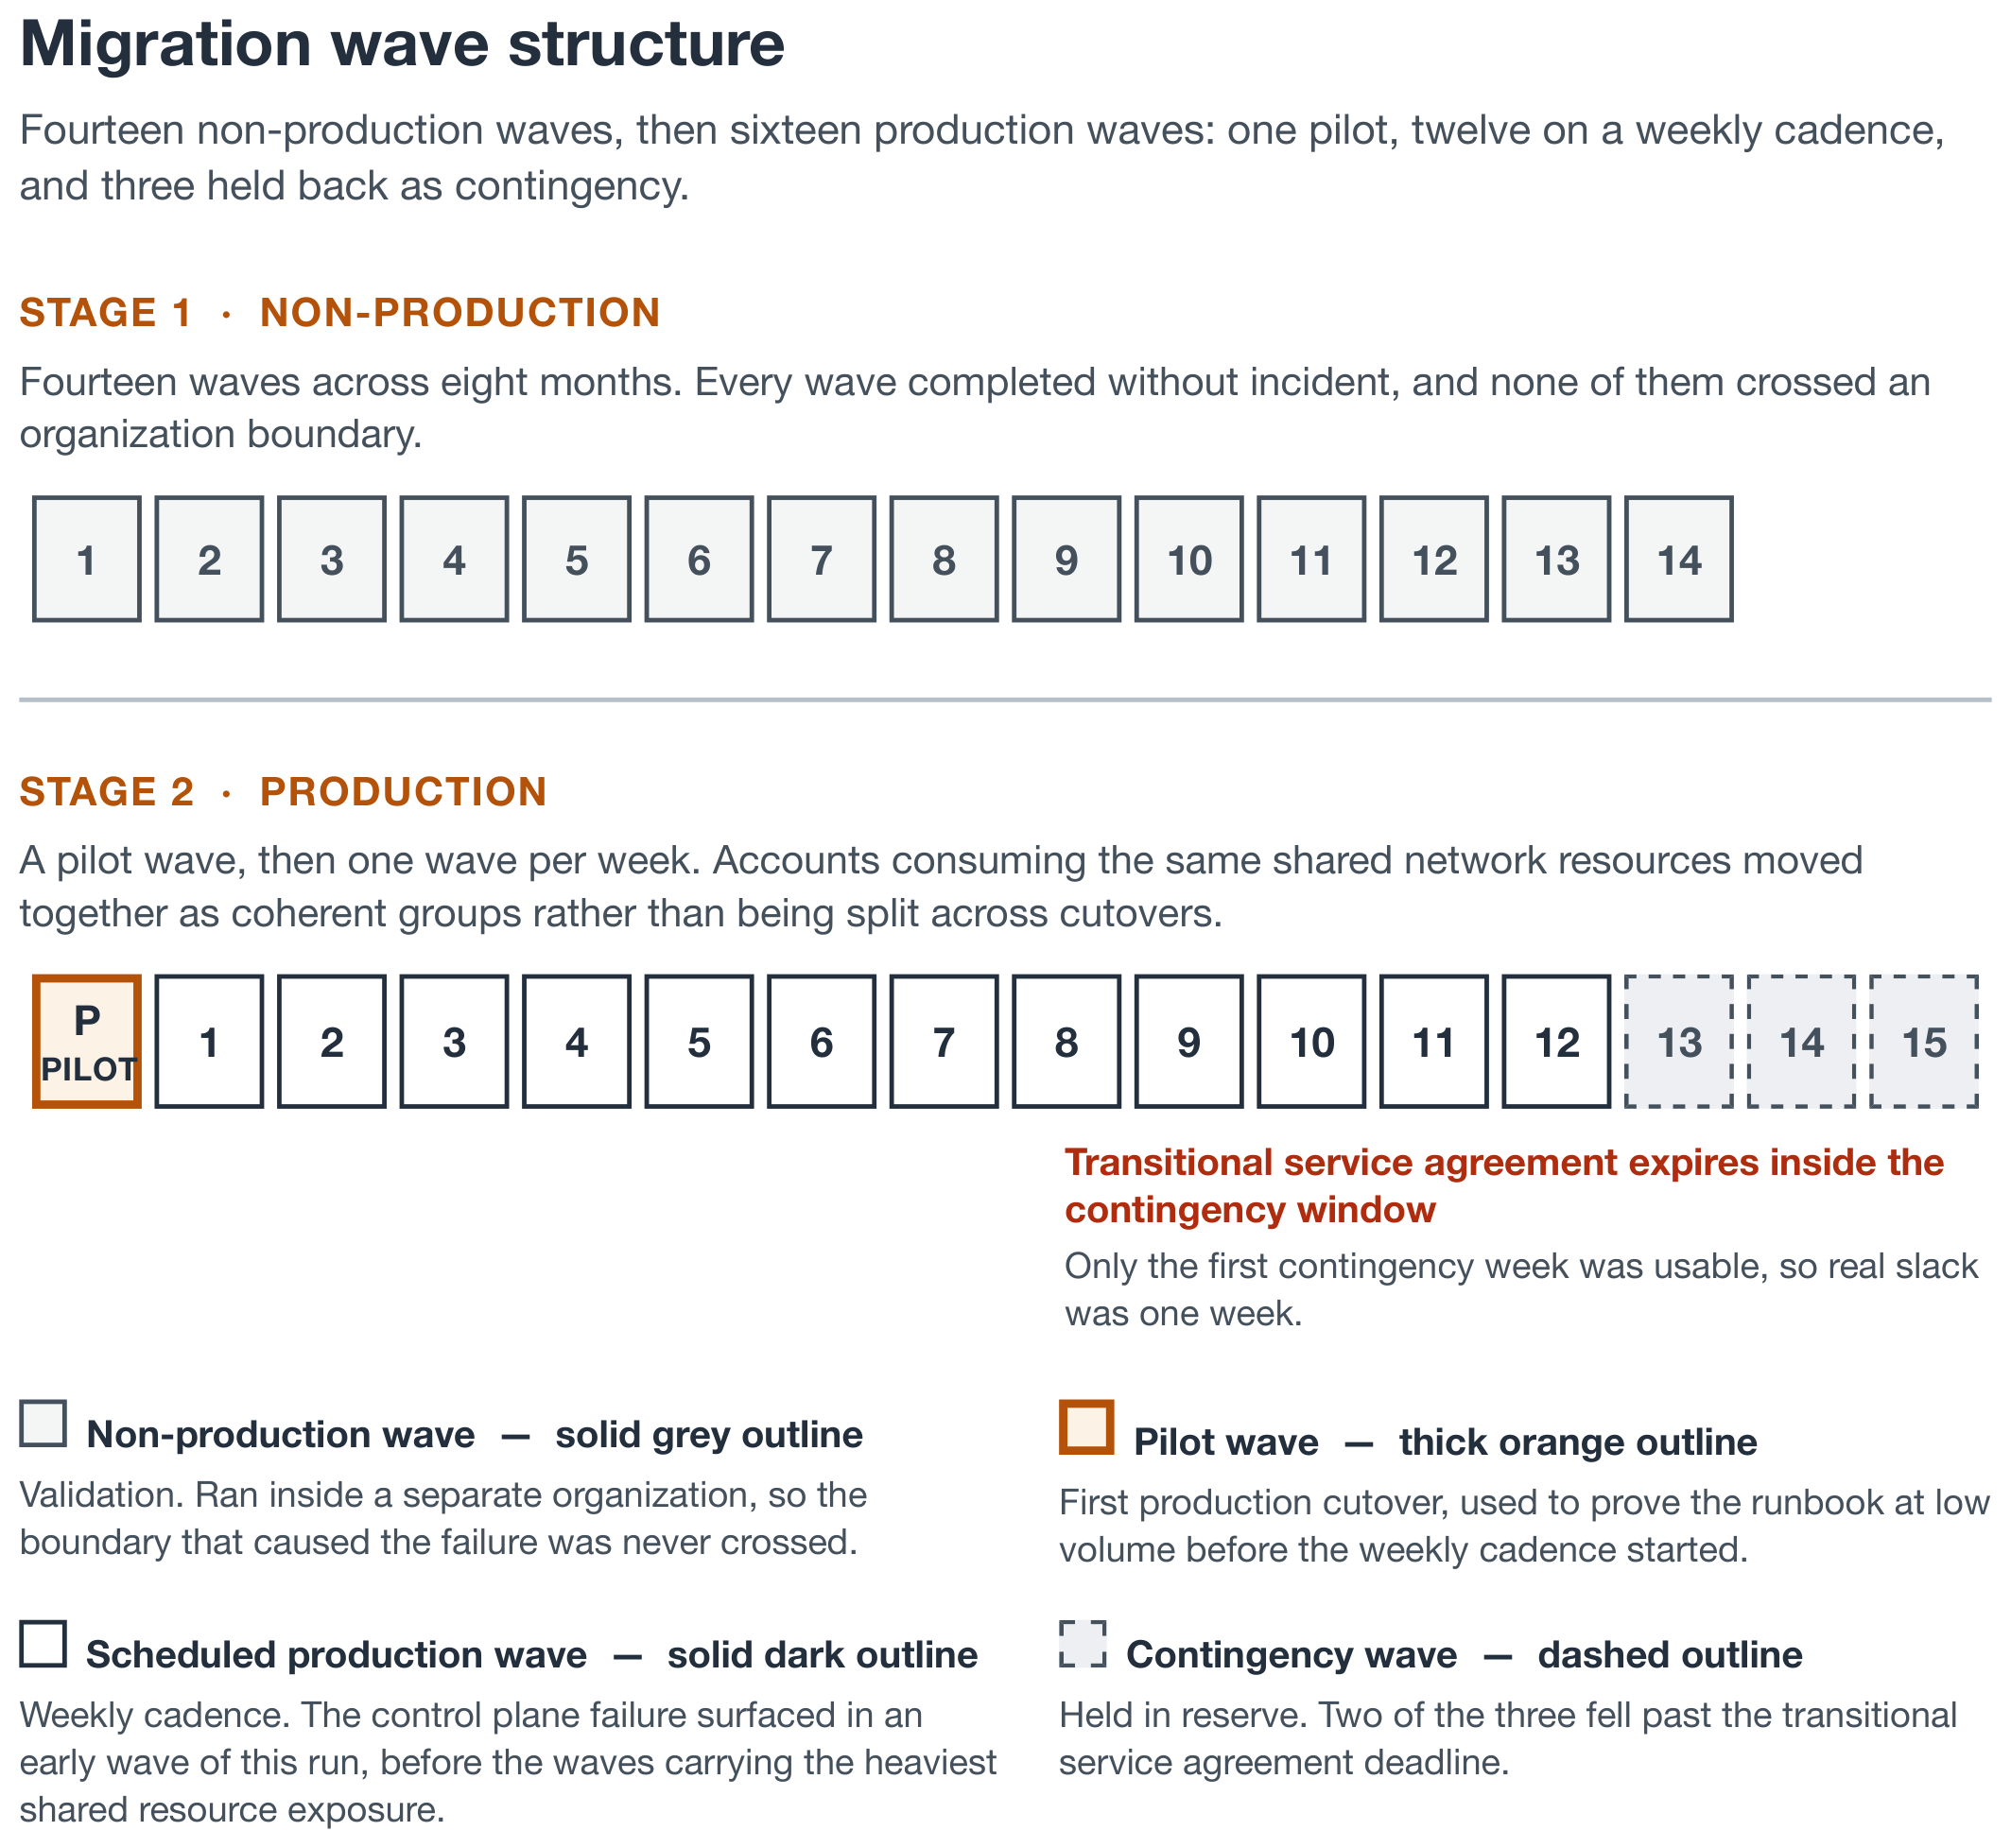
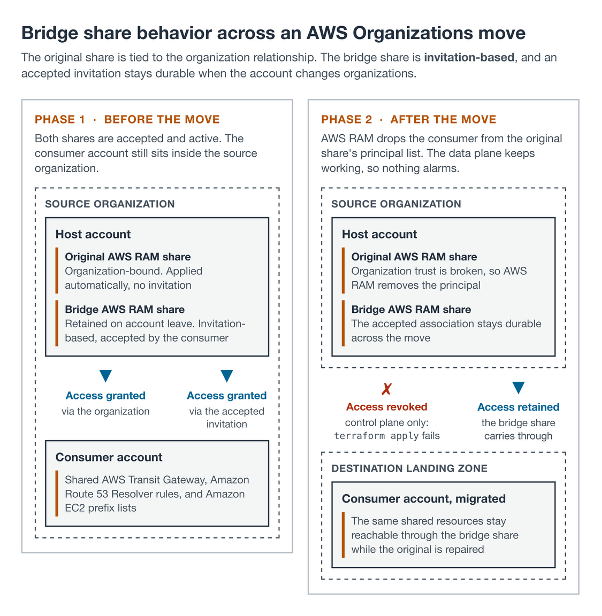
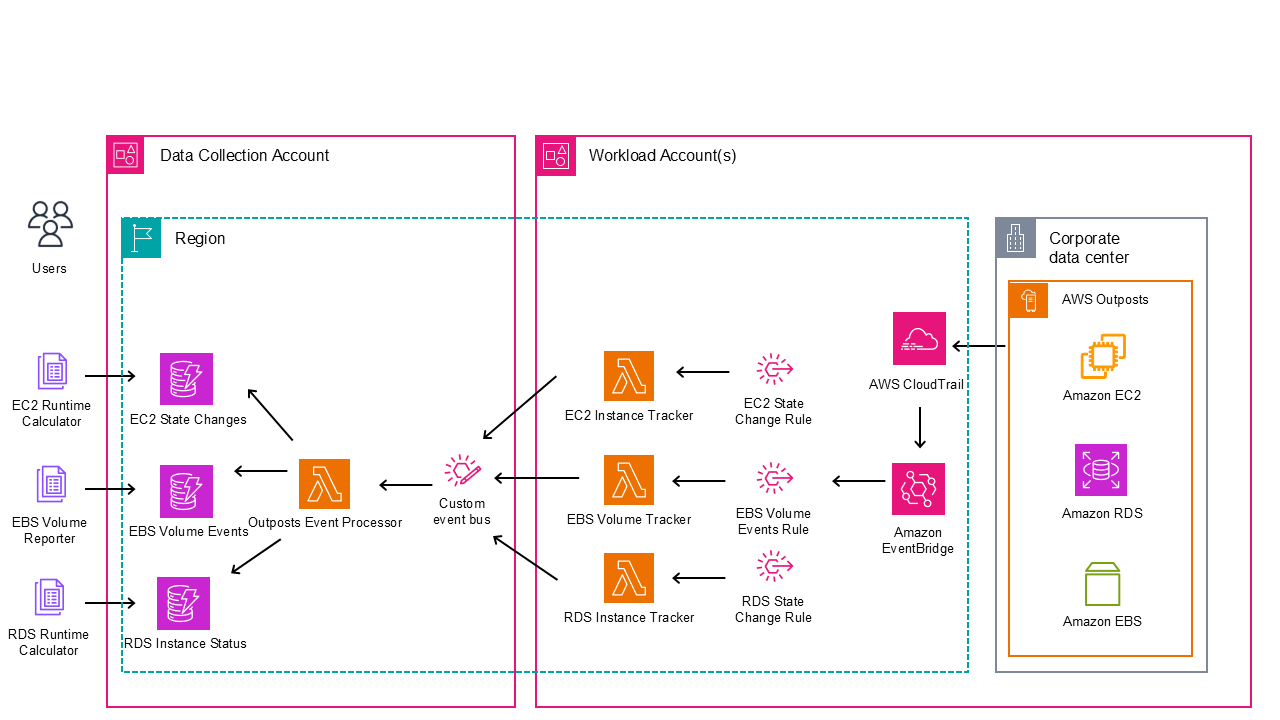
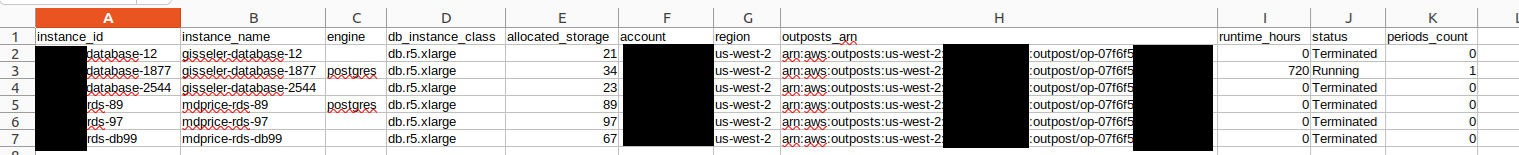


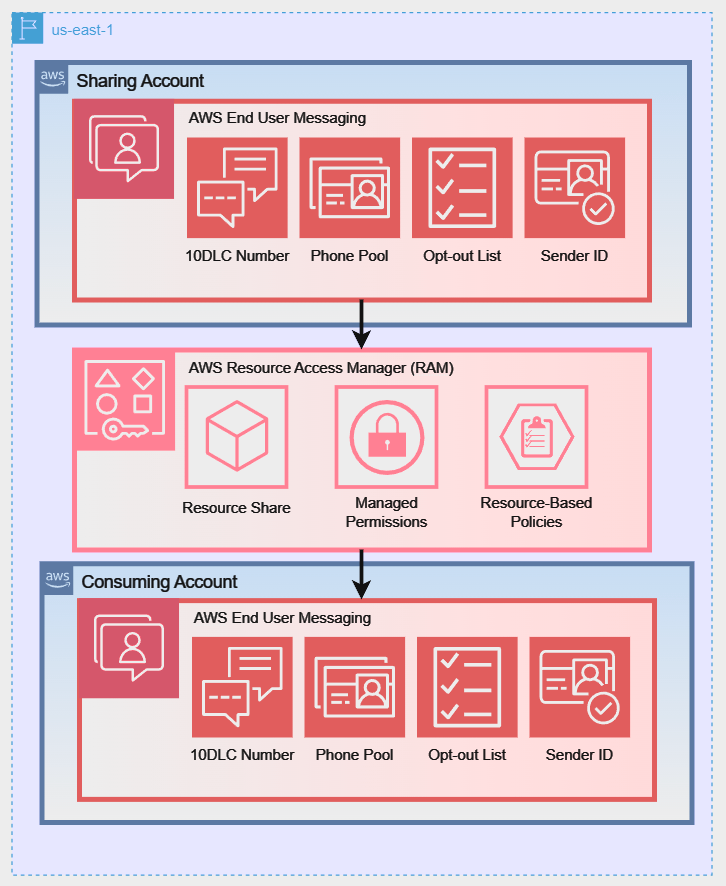
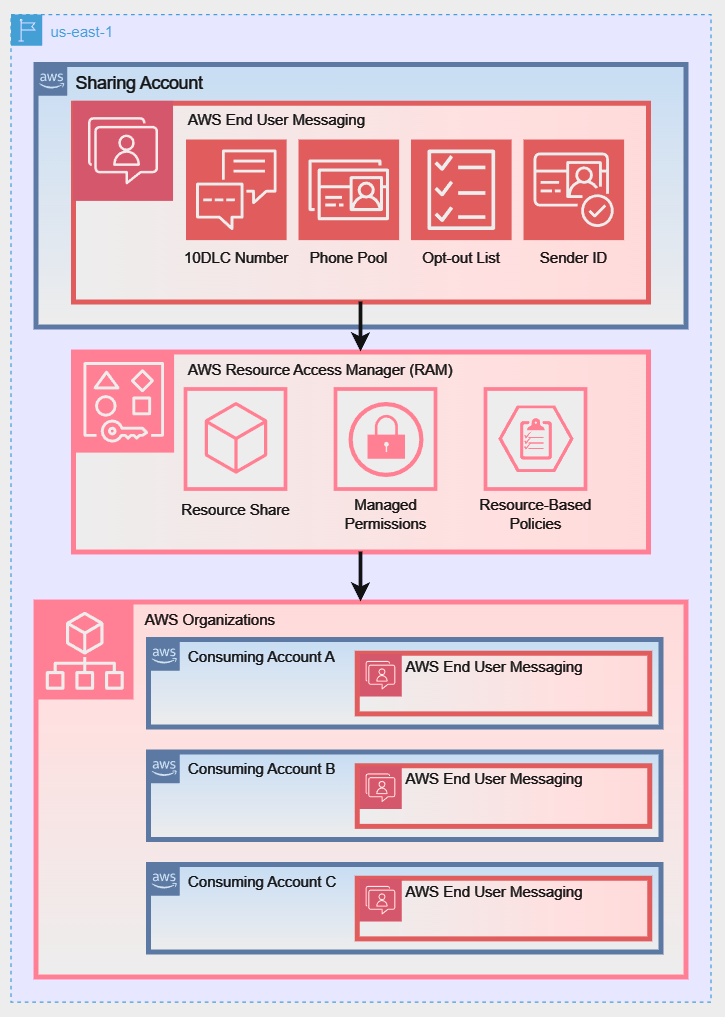
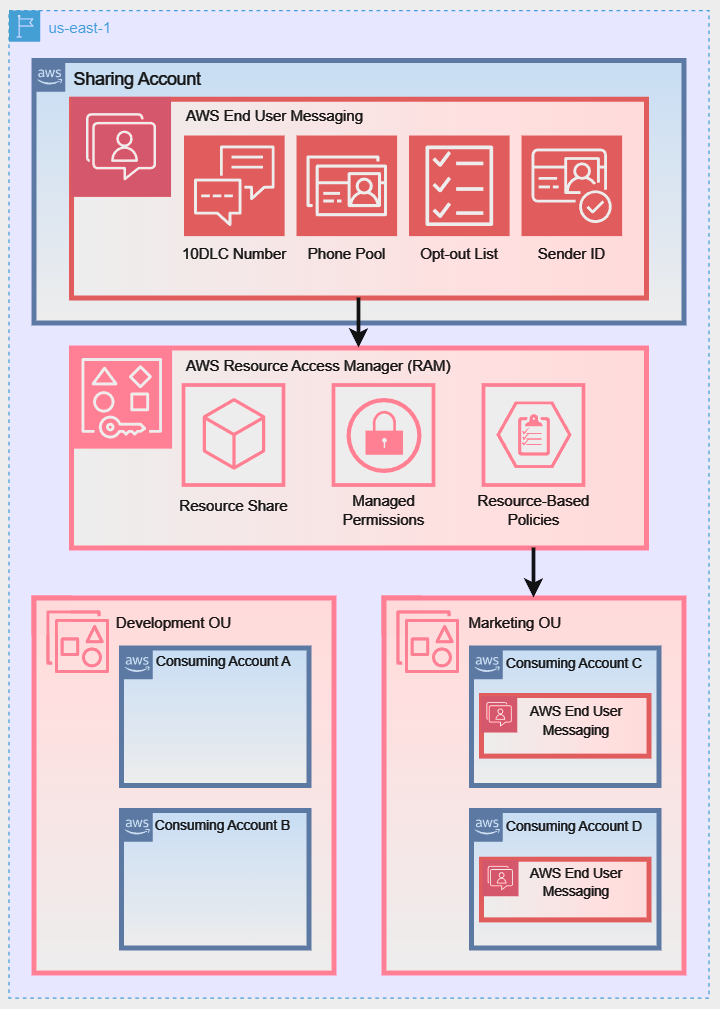
 AWS
 en


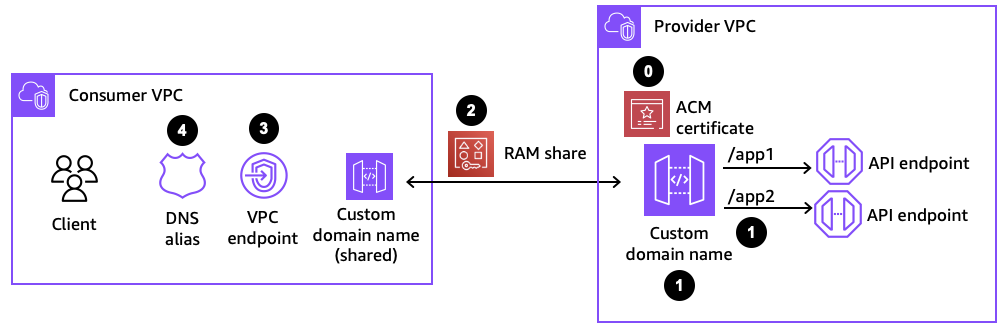
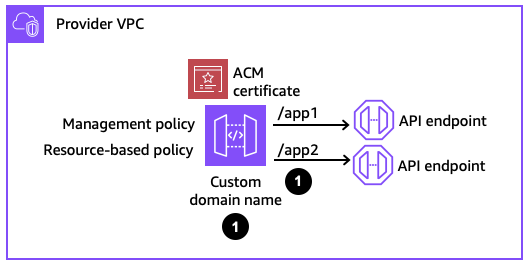
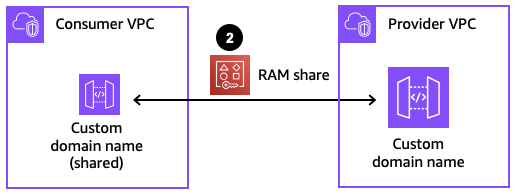


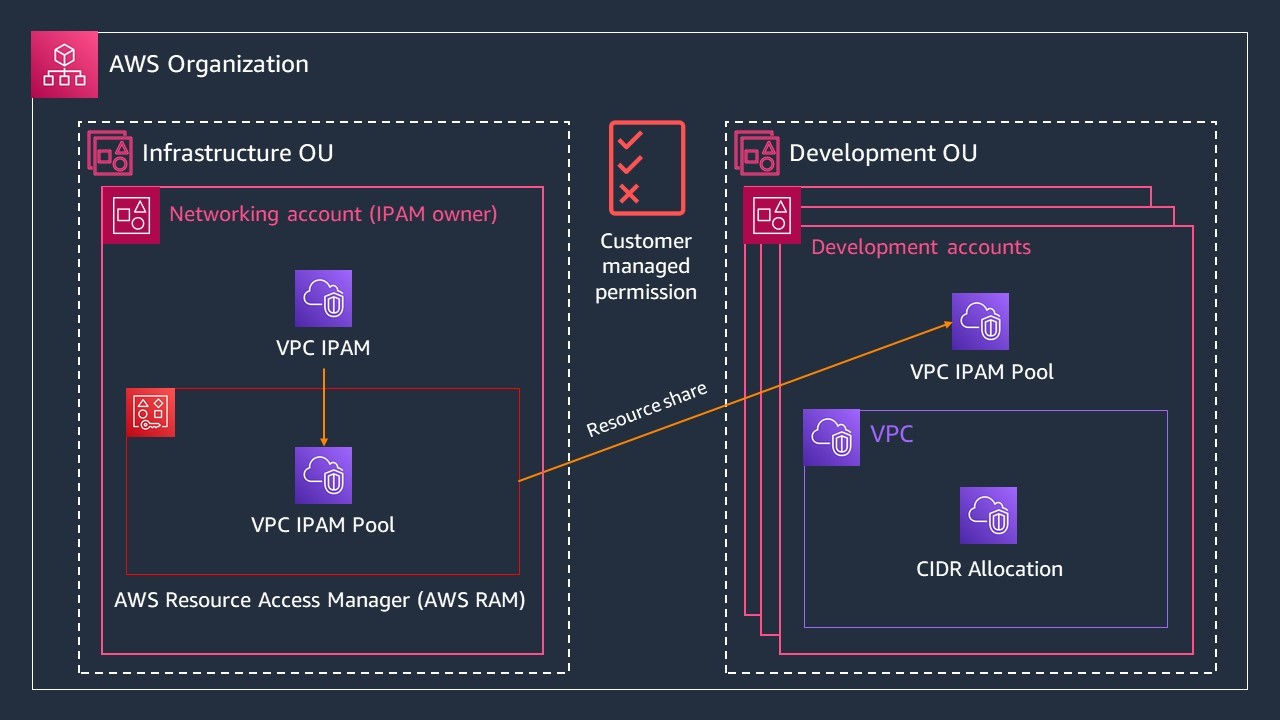
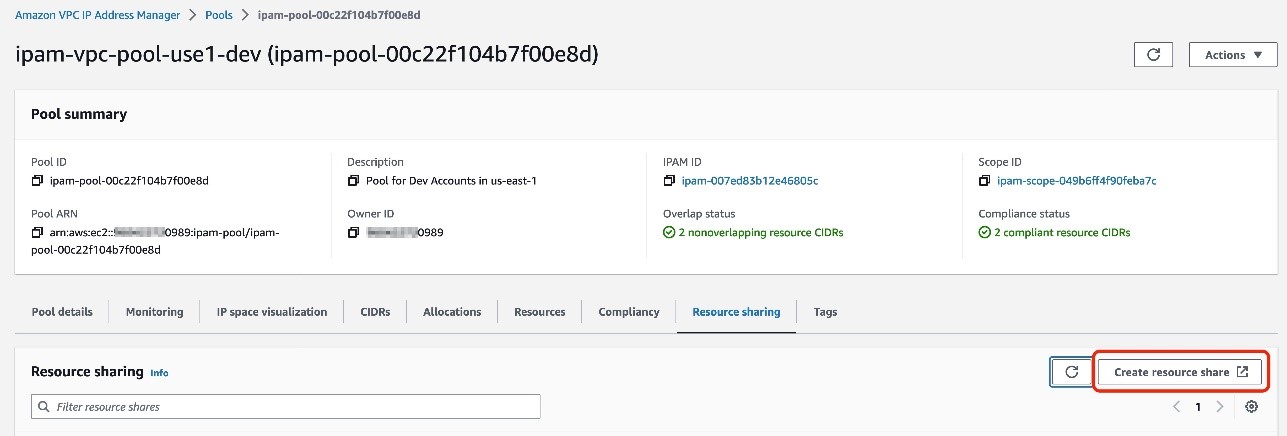
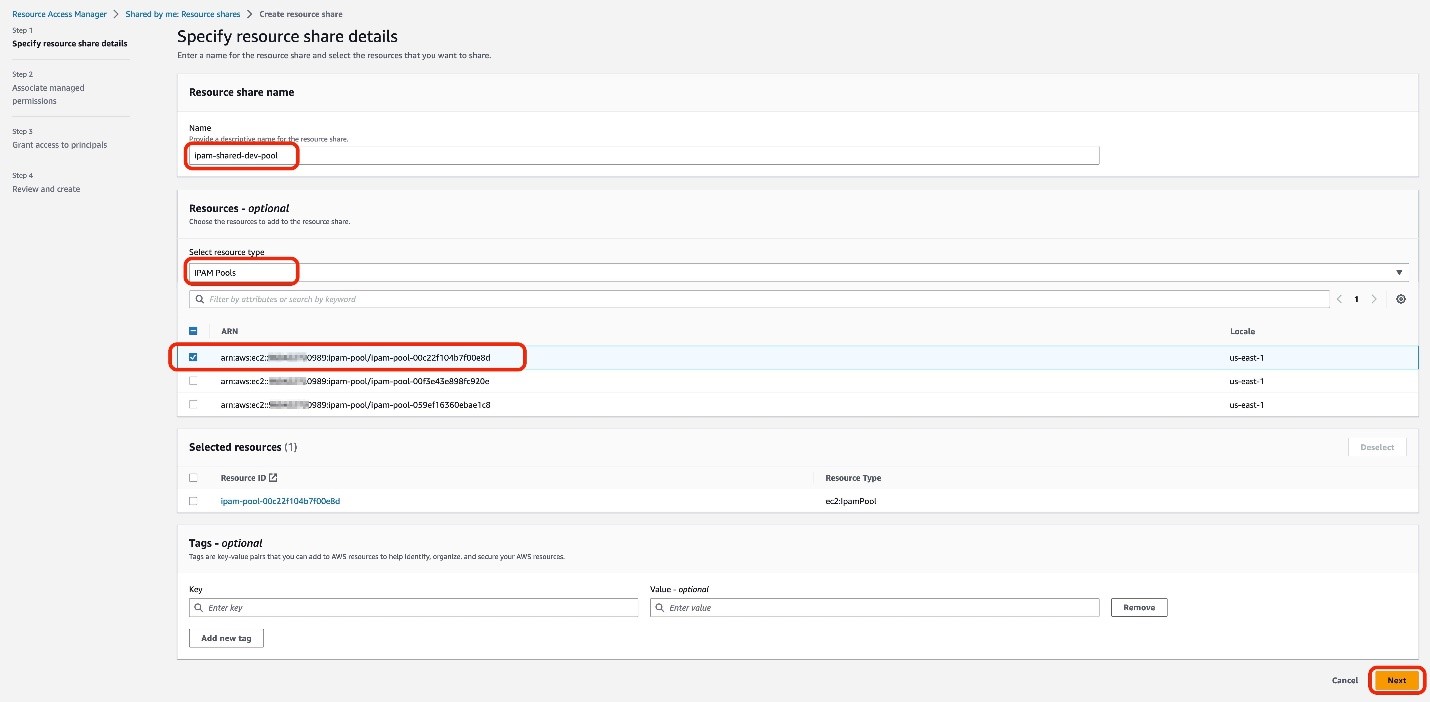
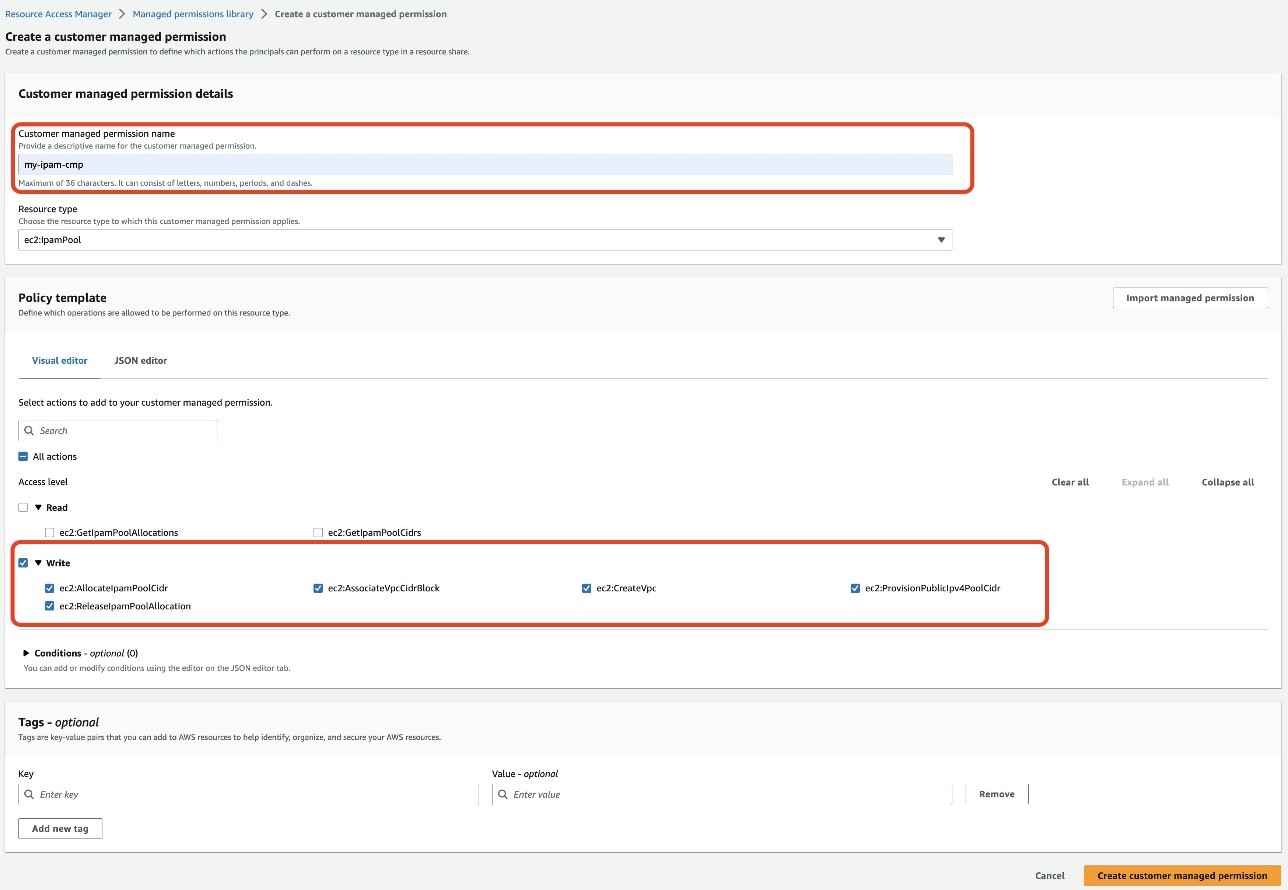
 .
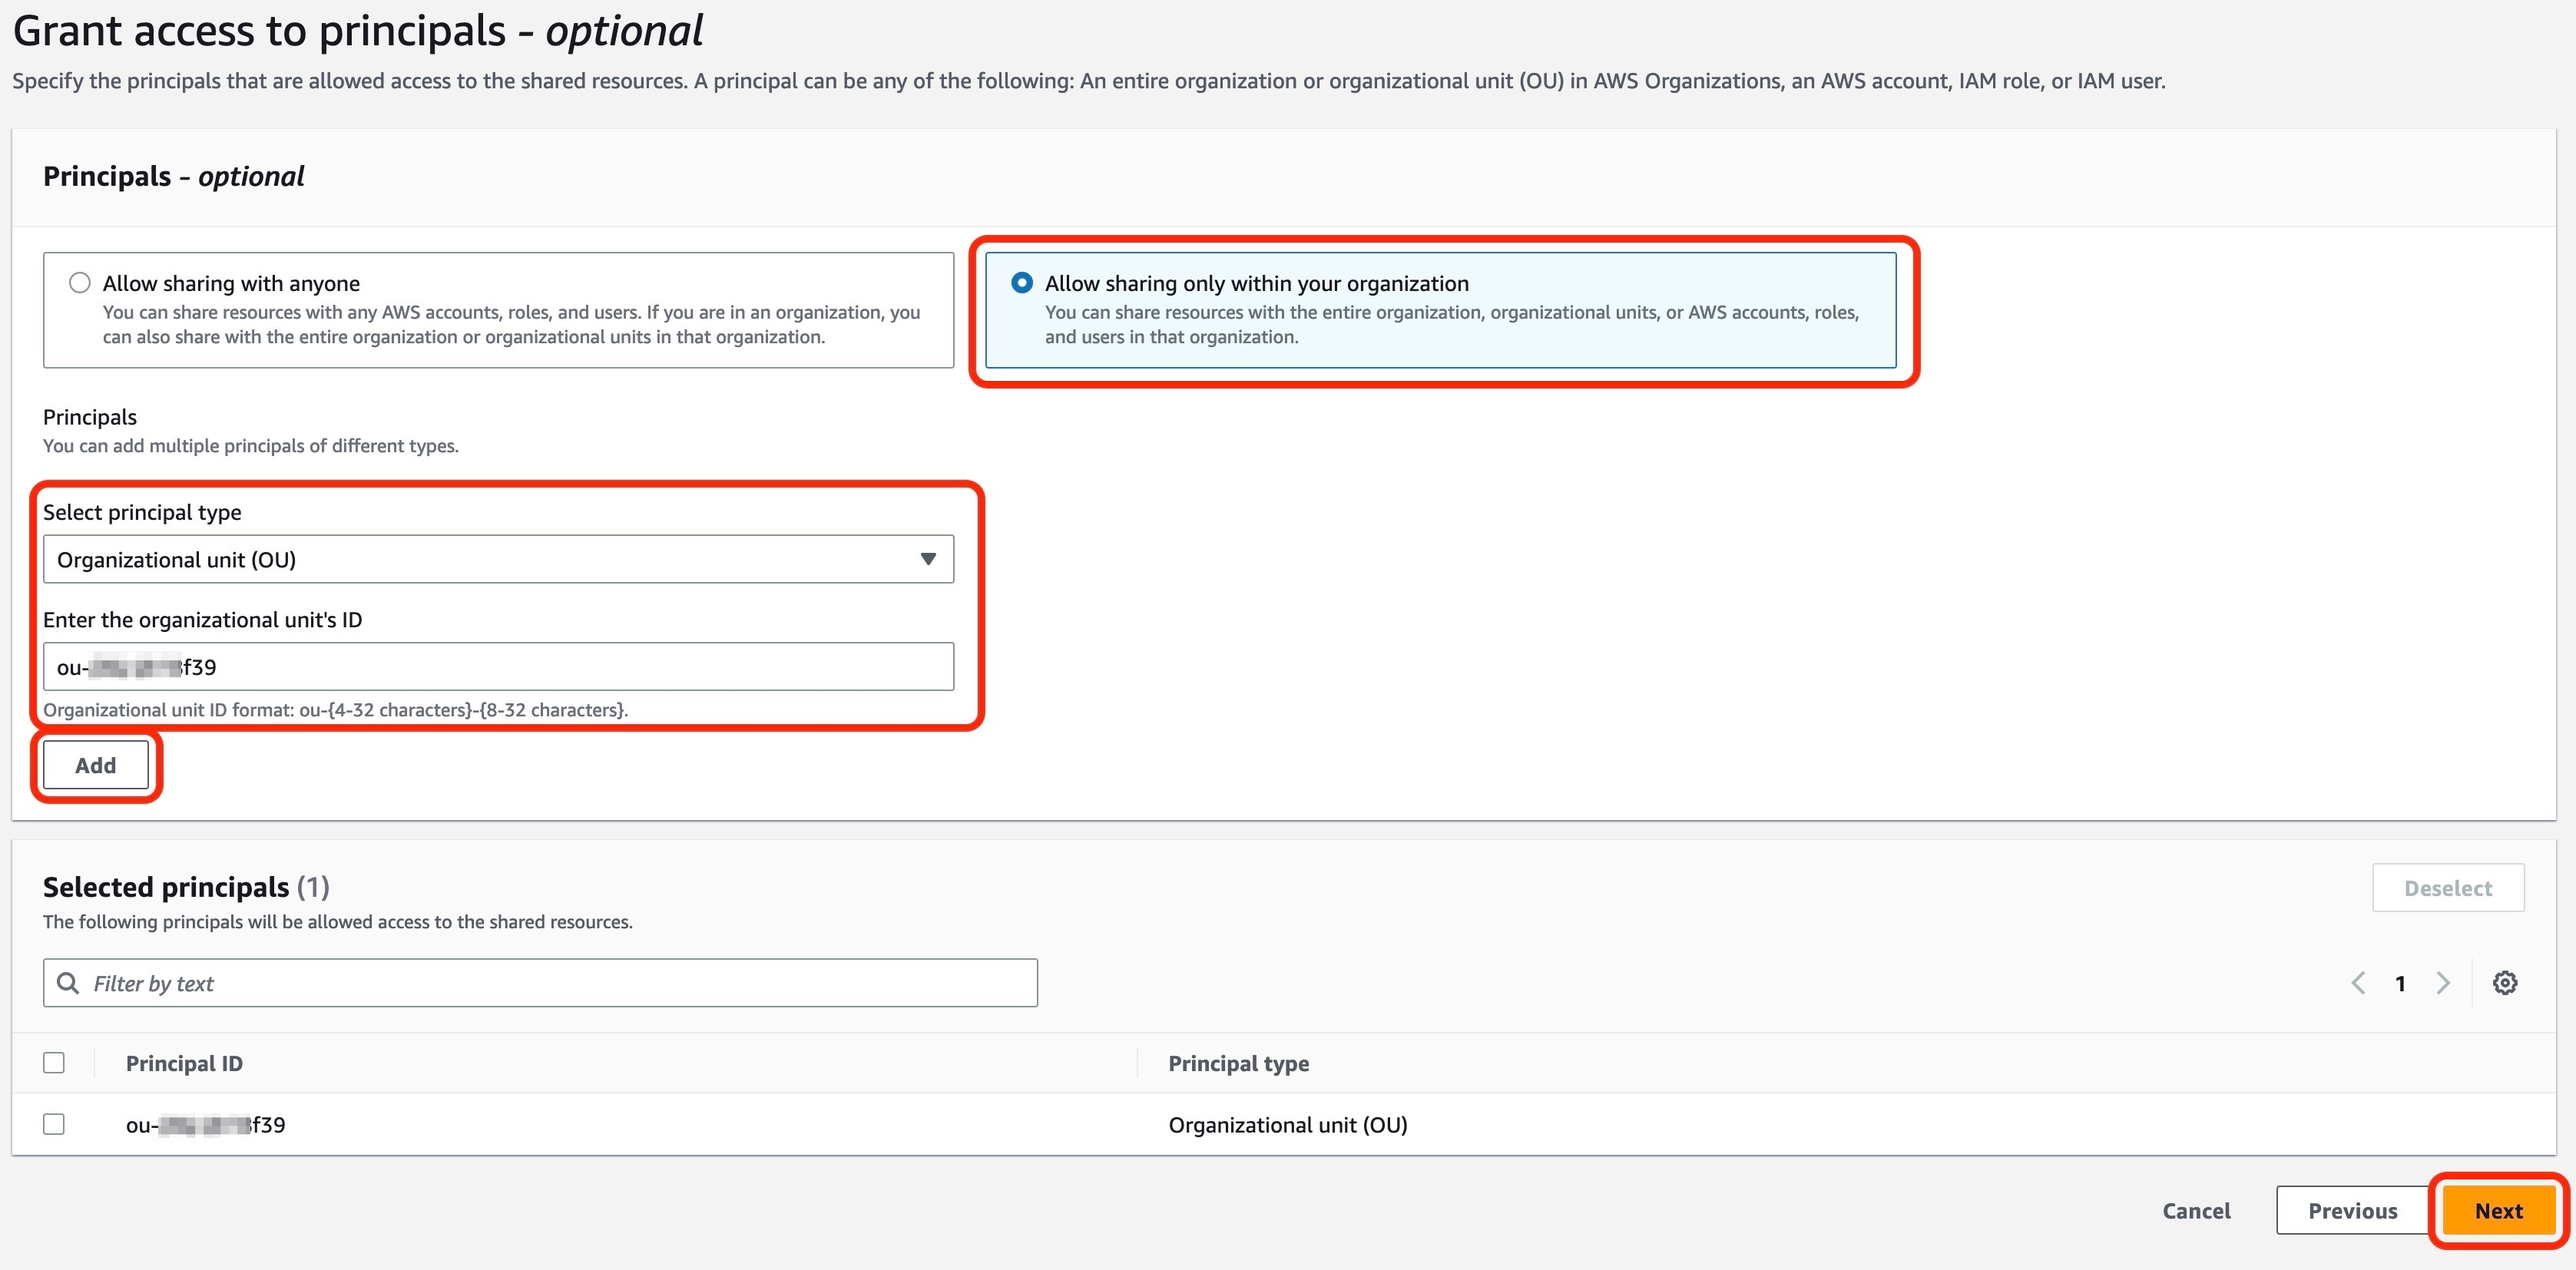
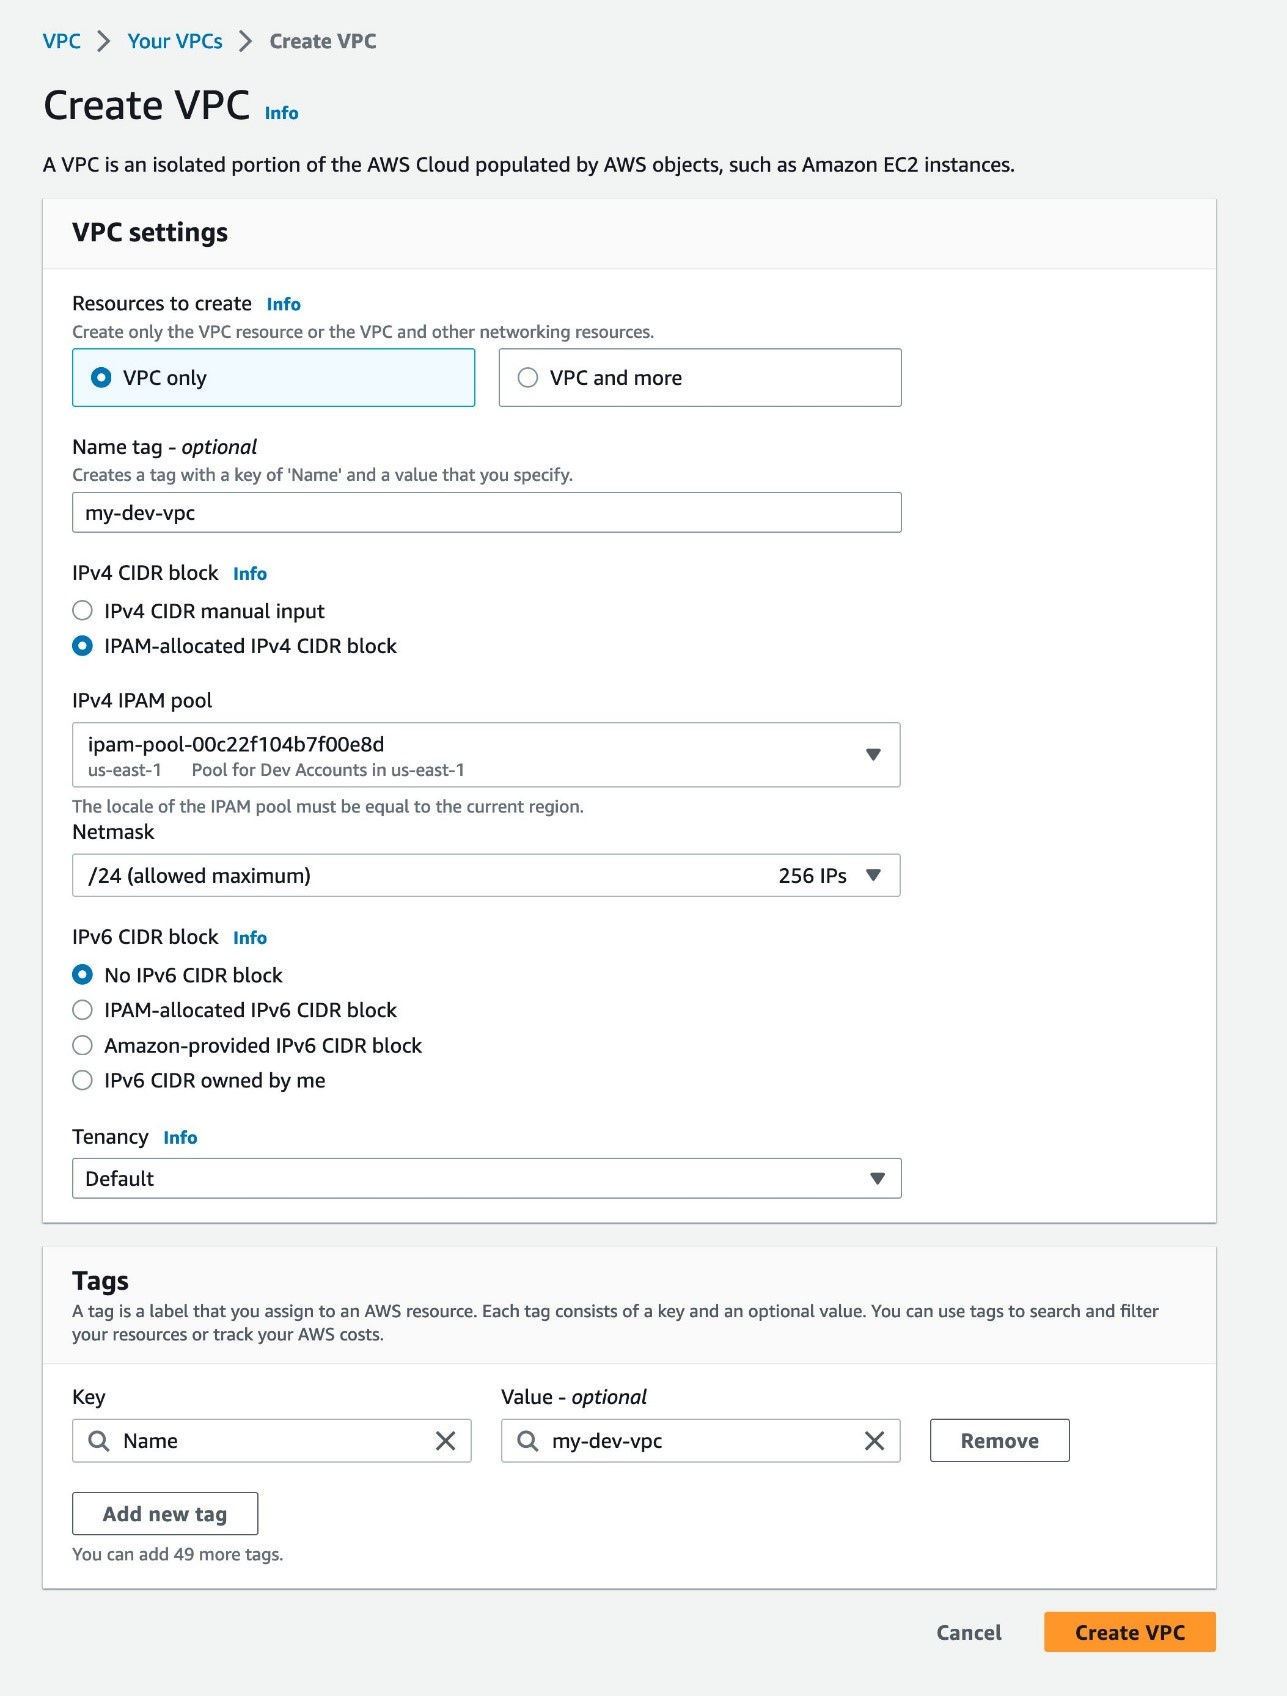
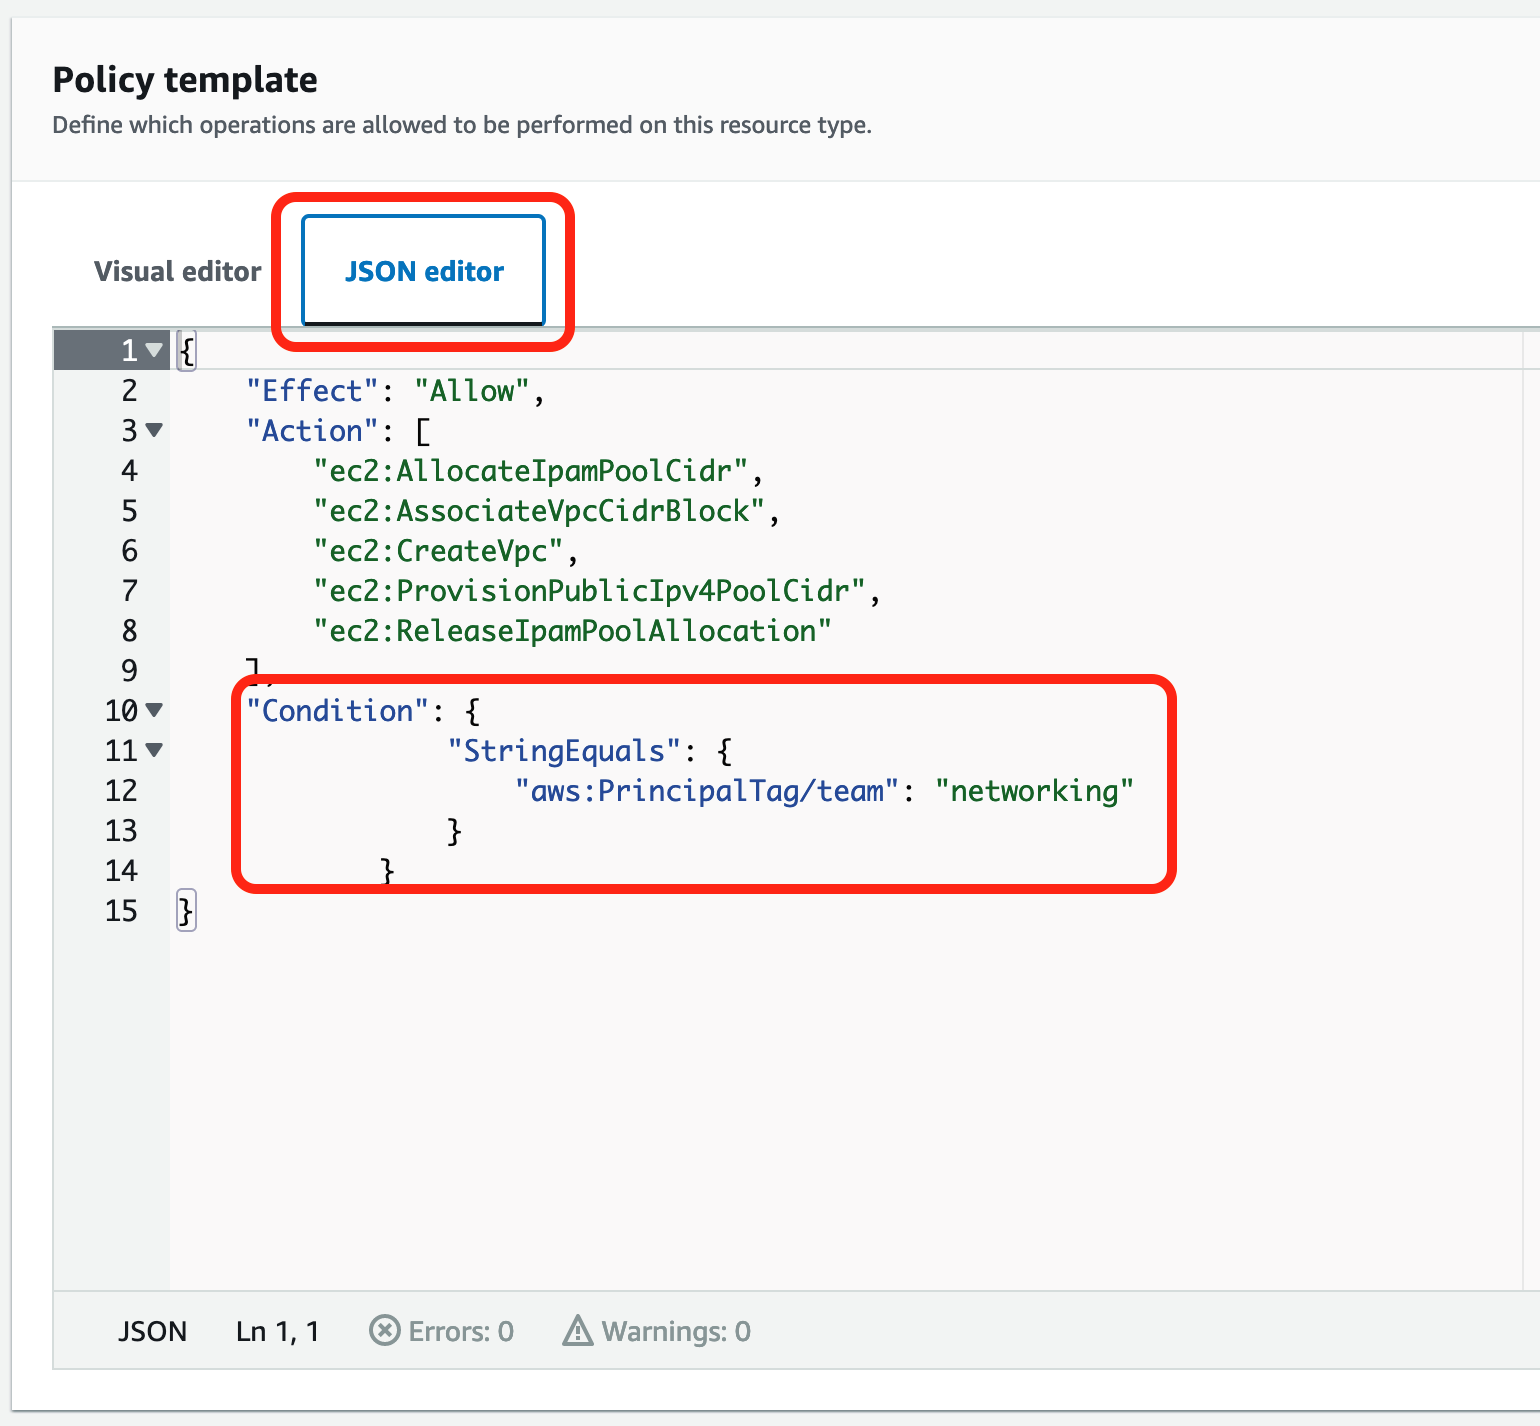


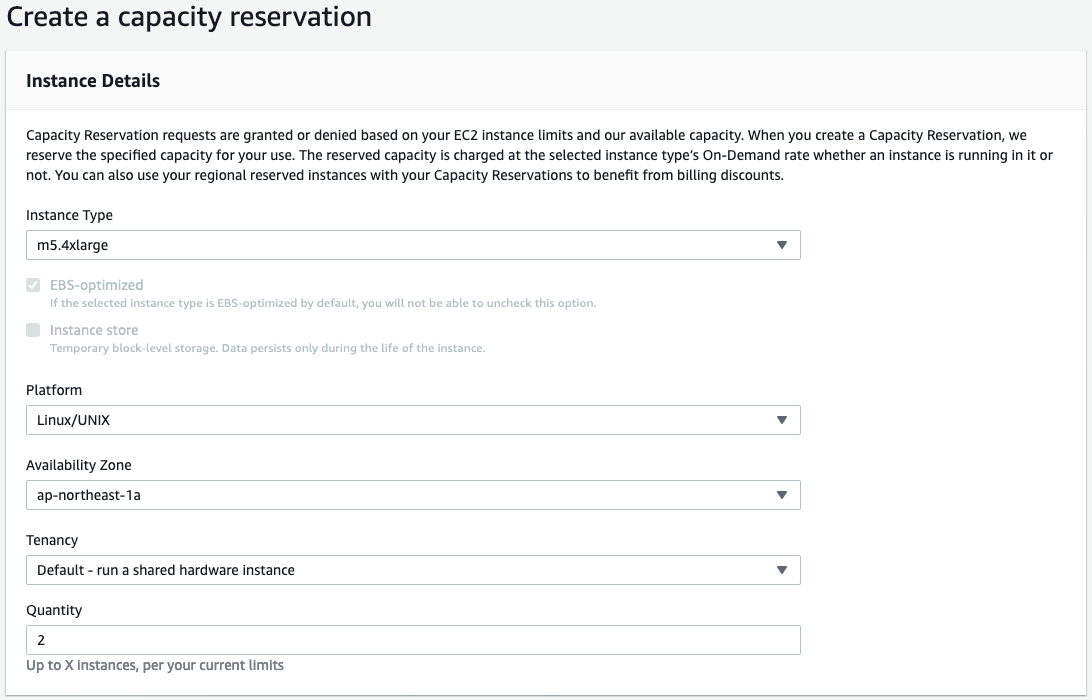
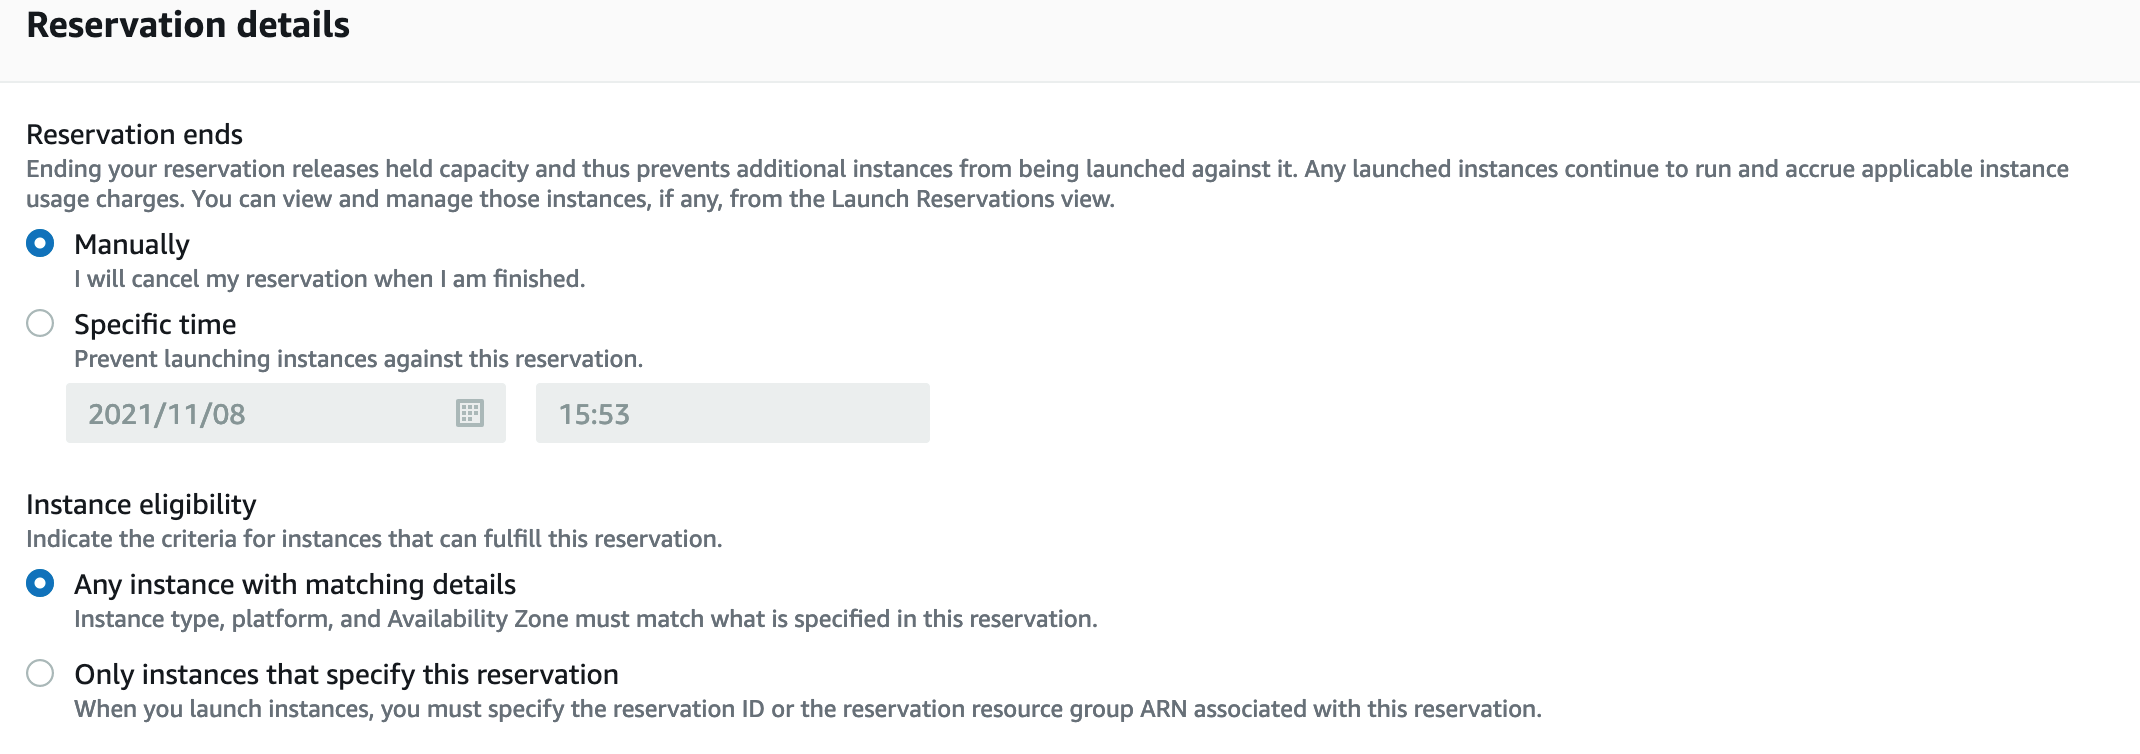
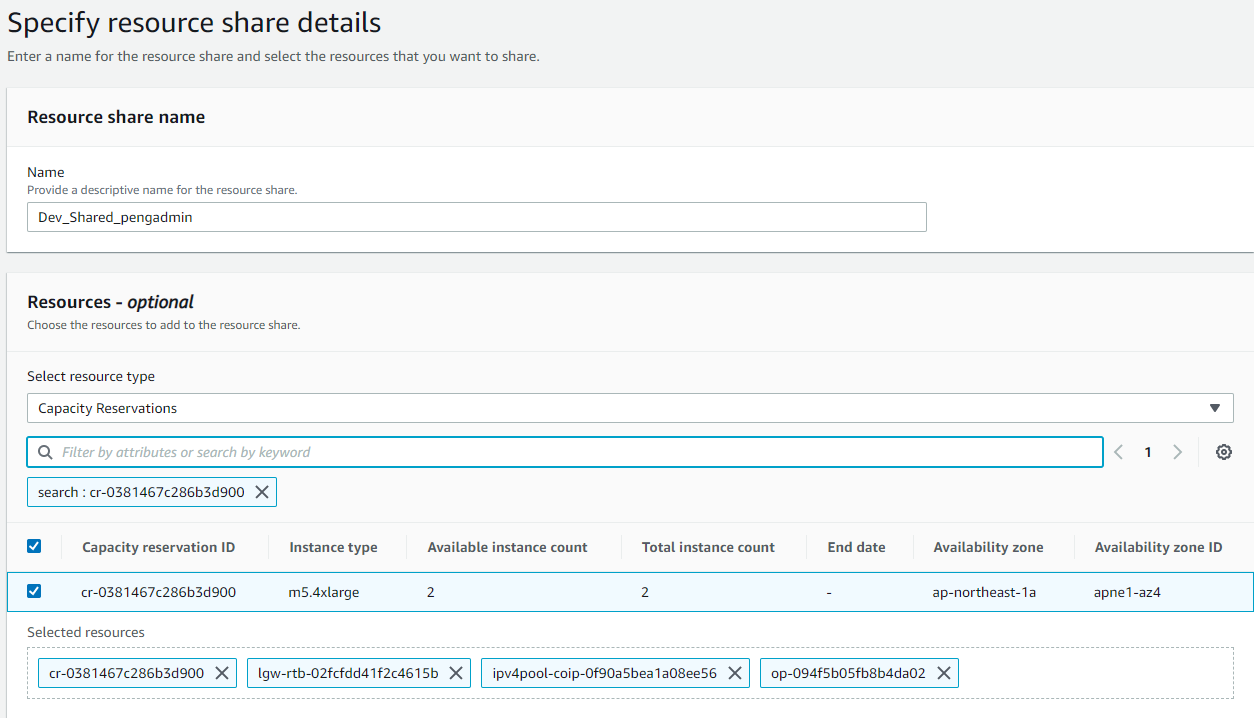
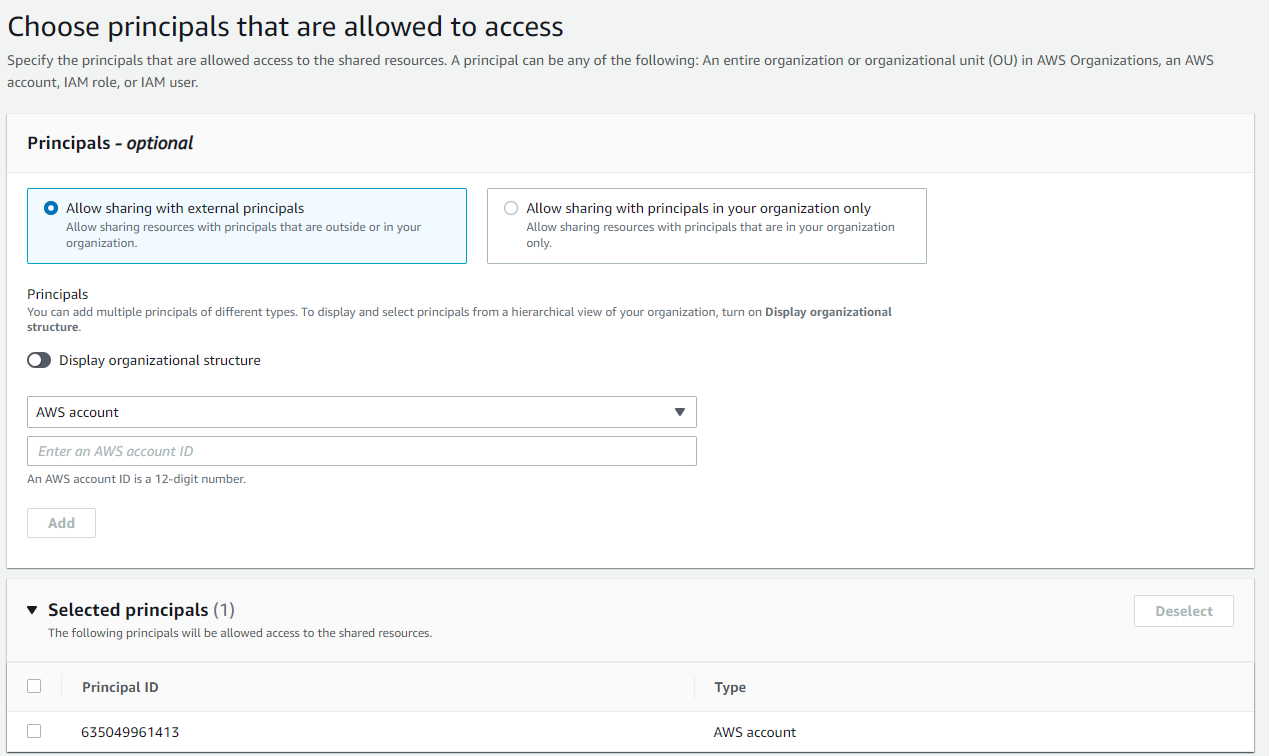


 Lotfi Mouhib is a Senior Solutions Architect working for the Public Sector team with Amazon Web Services. He helps public sector customers across EMEA realize their ideas, build new services, and innovate for citizens. In his spare time, Lotfi enjoys cycling and running.


