Tag Archives: Uncategorized

Details of Alan Turing’s Voice Encryption System

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/details-of-alan-turings-voice-encryption-system.html

Really interesting piece of cryptographic history:

In November 2023, a large cache of his wartime papers—nicknamed the “Bayley papers”—was auctioned in London for almost half a million U.S. dollars. The previously unknown cache contains many sheets in Turing’s own handwriting, telling of his top-secret “Delilah” engineering project from 1943 to 1945. Delilah was Turing’s portable voice-encryption system, named after the biblical deceiver of men. There is also material written by Bayley, often in the form of notes he took while Turing was speaking. It is thanks to Bayley that the papers survived: He kept them until he died in 2020, 66 years after Turing passed away.

Introducing self-managed Amazon S3 buckets for AWS Lambda function code

Post Syndicated from Doug Perkes original https://aws.amazon.com/blogs/compute/introducing-self-managed-amazon-s3-buckets-for-aws-lambda-function-code/

If you manage Lambda functions at scale, you’ve likely hit the 75 GB code storage limit or explained to your security team why deployment artifacts live in an S3 bucket you don’t control. Today, we’re announcing self-managed Amazon S3 buckets for AWS Lambda deployment packages. Lambda reads your code directly from your bucket, eliminating quota pressure and giving you full security control.

Previously, the default AWS-managed code storage created three challenges at scale. First, all copies count toward your 75 GB code storage quota. Second, you cannot apply your own encryption, access controls, or compliance tags to the internal bucket. Third, the copy cannot be incorporated into your disaster recovery strategies.

With self-managed S3 buckets, Lambda reads your function code directly from your bucket. No copy, no duplication. Your S3 object becomes the single source of truth for your functions. Deployment packages no longer count against your account’s code storage limit. You manage the bucket’s security and compliance posture: choosing the encryption, defining the access policies, managing lifecycle transitions, and maintaining the audit trail. And because you own the bucket, you can use S3 Cross-Region Replication to maintain fallback copies of your code in a secondary Region, so that your functions remain deployable even if your primary Region experiences an issue. Using self-managed S3 buckets also results in a faster time to first invoke for new functions and after function updates, because Lambda no longer needs to copy your zip package to a Lambda-managed S3 bucket.

You can use this feature today in all AWS standard regions where Lambda is available, at no additional charge beyond your standard Amazon S3 storage and request costs. Let’s look at some use cases, how it works, and how to use it at scale.

Use cases

Here are a few patterns where owning your deployment bucket makes a real difference.

CI/CD pipelines and artifact management

With self-managed storage, your CI/CD pipeline uploads once, and Lambda references the same object. One set of lifecycle rules and access controls covers all artifacts, and rollbacks mean pointing the function to a previous S3 object version.

Multi-account and multi-team architectures

Organizations using AWS Organizations often separate workloads into multiple accounts: a development account, a staging account, and a production account. They centralize shared resources in a tooling or shared-services account.

Self-managed buckets integrate naturally with this pattern:

  • Store all deployment artifacts in a central “artifact account” bucket.
  • Grant cross-account s3:GetObject access to Lambda execution roles in each workload account through bucket policies.
  • Maintain a single inventory of what code is deployed where, managed by your platform or DevOps team.
  • Enforce consistent encryption, versioning, and retention policies from one place.

Disaster recovery and business continuity

Because your deployment artifacts live in a bucket you own, you can use the built-in replication features of S3, Cross-Region Replication (CRR) or Same-Region Replication (SRR), to maintain copies of your code artifacts in backup locations. Combined with S3 Versioning and Object Lock, this gives you a durable, tamper-proof code archive that supports rapid recovery if a deployment is accidentally corrupted or deleted.

How it worked before

When you deploy a Lambda function using a .zip deployment package stored in Amazon S3, the process has traditionally worked like this:

  1. You upload your .zip deployment package to your S3 bucket.
  2. You call CreateFunction or UpdateFunctionCode, specifying the S3 bucket and S3 key.
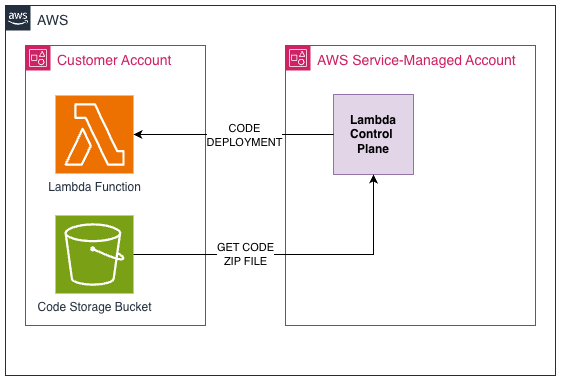
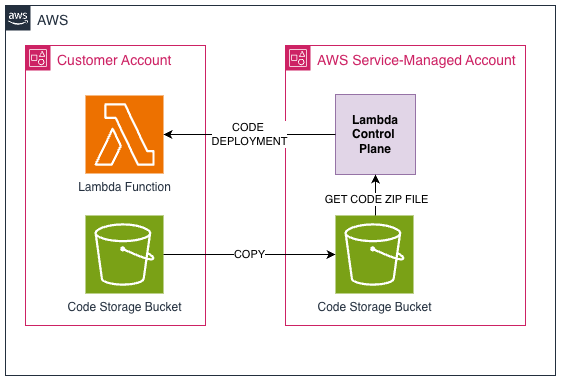
  3. Lambda copies the .zip artifact from your bucket into an internal, service-managed bucket.
  4. Lambda uses this copy to create the optimized version of your function that runs at invocation time.
  5. The copied artifact counts toward your account’s 75 GB code storage quota.

Diagram showing standard Lambda deployment flow where Lambda copies the zip package to an internal bucket

Figure 1 — Standard Lambda deployment

This model is straightforward and works well for most workloads. However, it creates three friction points at scale:

  • Storage quota pressure: Every deployment package copy counts toward your account’s 75 GB total code storage limit. Organizations with hundreds of functions and multiple published versions can exhaust this quota.
  • No control over stored artifacts: You cannot configure encryption (beyond the service default), access logging, lifecycle policies, Object Lock, or compliance tags on the internal bucket.
  • Redundant storage: Your original artifact remains in your bucket while a copy lives in the Lambda bucket used for provisioning new instances of your Lambda function.

What’s new: REFERENCE mode

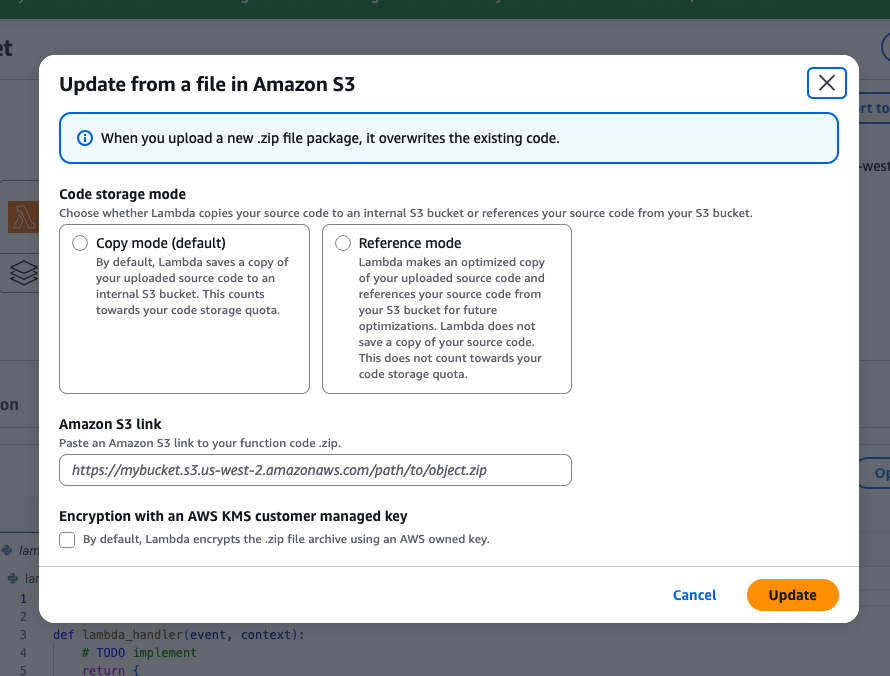
This launch introduced a new function configuration setting, S3ObjectStorageMode. The default value is COPY, which provides the existing behavior described in the preceding section. To enable self-managed S3 buckets, set S3ObjectStorageMode to REFERENCE when creating or updating a function. In this mode, Lambda no longer copies your deployment package. Instead, it stores a reference to your S3 object and reads the code directly from your bucket when needed. If you do not specify S3ObjectStorageMode, Lambda still takes a copy by default.

Diagram showing Lambda deployment with self-managed S3 storage where Lambda references the object directly

Figure 2 — Lambda deployment with self-managed storage

This gives you:

  • No quota consumption. Deployment packages in your bucket don’t count against the 75 GB Function and layer storage account limit.
  • Improved performance. Lambda no longer copies the code to an internal bucket, so function creation and updates are faster.
  • Full security and compliance control. Apply your own bucket policies, encryption, Object Lock, versioning, access logging, and compliance tags.
  • Single source of truth. Your S3 object is the canonical artifact with no additional copies and no drift.
  • Disaster recovery options. Use S3 Cross-Region Replication to maintain fallback copies in a secondary Region.

How it works

To use this feature, specify the S3ObjectStorageMode parameter when creating or updating your function.

Creating a new function (AWS CLI):

aws lambda create-function \
  --function-name my-function \
  --runtime python3.13 \
  --role arn:aws:iam::123456789012:role/my-lambda-role \
  --handler app.handler \
  --code S3Bucket=amzn-s3-demo-bucket,S3Key=deployments/my-function.zip,S3ObjectVersion=abc123,S3ObjectStorageMode=REFERENCE

Updating an existing function:

aws lambda update-function-code \
  --function-name my-function \
  --s3-bucket amzn-s3-demo-bucket \
  --s3-key deployments/my-function.zip \
  --s3-object-version def456 \
  --s3-object-storage-mode REFERENCE

AWS Identity and Access Management permissions required for self-managed code storage

AWS Identity and Access Management (IAM) permissions

Lambda needs permission to read the deployment package from your bucket. You can grant access through an S3 bucket policy.

S3 bucket policy

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "LambdaSelfManagedCodeAccess",
      "Effect": "Allow",
      "Principal": {
        "Service": "lambda.amazonaws.com"
      },
      "Action": [
        "s3:GetObject",
        "s3:GetObjectVersion"
      ],
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket/deployments/my-function.zip",
      "Condition": {
        "ArnLike": {
          "aws:SourceArn": "arn:aws:lambda:us-east-1:123456789012:function:my-function"
        }
      }
    }
  ]
}

We recommend including the aws:SourceArn condition key scoped to your specific function ARN to allow for least-privileged access. Note the Resource is scoped to the exact S3 key rather than a wildcard prefix. This follows least-privilege and matches how the aws:SourceArn condition locks down which function can access which object.

Bucket requirements

Your S3 bucket must meet the following requirements:

  • Versioning (required). You must enable S3 versioning to make sure that Lambda references a specific, immutable artifact and to protect against accidental overwrites.
  • Encryption. The following encryption types are supported: SSE-S3, SSE-KMS (including customer-managed KMS keys), and DSSE-KMS. If you use SSE-KMS, the Lambda principal must have kms:Decrypt permission on the key.
  • Object Lock. Supported. You can apply Object Lock in Compliance or Governance mode to prevent accidental deletion of deployment artifacts.
  • Access logging. You can enable S3 server access logging or AWS CloudTrail data events to audit every time Lambda reads your code.

What happens when the object is unavailable

Lambda periodically accesses the source object from your S3 bucket to reoptimize your function code. You must maintain access to the source object for your function to remain active.

If Lambda loses access to the source object for a function, the function transitions to the Inactive state. To restore the function, restore access to the source object and then update the function.

Performance considerations

Lambda functions with self-managed code storage behave the same as standard Lambda functions with one difference during function creation and update. Lambda does not copy your deployment package to a Lambda-managed S3 bucket. In our testing with a 200MB Python 3.13 function, functions using self-managed storage showed function creation times approximately 5s less than the default COPY mode. Reading directly from your S3 bucket without an intermediate copy step can provide a modest advantage, particularly for larger deployment packages.

Getting started with infrastructure as code

Self-managed code storage can be implemented using infrastructure-as-code tooling with either the AWS CLI or AWS CloudFormation today.

AWS CLI

aws lambda create-function \
  --function-name my-function \
  --runtime python3.13 \
  --role arn:aws:iam::123456789012:role/my-lambda-role \
  --handler app.handler \
  --code S3Bucket=amzn-s3-demo-bucket,S3Key=deployments/my-function.zip,S3ObjectVersion=abc123,S3ObjectStorageMode=REFERENCE \
  --region us-east-1

AWS CloudFormation

MyFunction:
  Type: AWS::Lambda::Function
  Properties:
    FunctionName: my-function
    Runtime: python3.13
    Handler: app.handler
    Role: !GetAtt MyLambdaRole.Arn
    Code:
      S3Bucket: amzn-s3-demo-bucket
      S3Key: deployments/my-function.zip
      S3ObjectVersion: abc123
      S3ObjectStorageMode: REFERENCE

Using it at scale

Once you adopt self-managed S3 buckets for your Lambda deployment packages, your artifact bucket grows over time as you deploy new versions of your functions. This section covers strategies for managing that growth efficiently, keeping your versions organized, and planning for cross-Region deployments.

Managing artifact lifecycle with S3 lifecycle policies

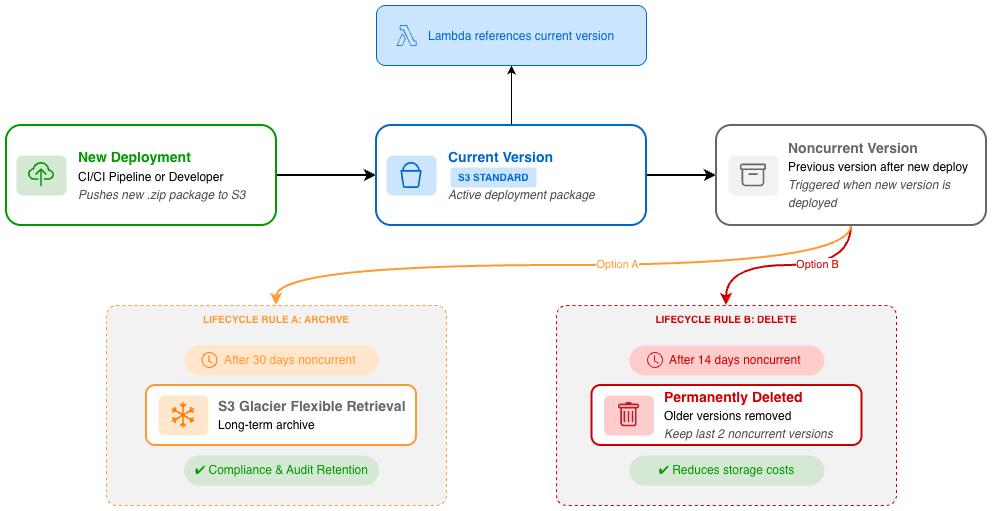
Every time you update a function’s code, S3 creates a new object version in your bucket. The previous objects don’t disappear. They accumulate. Without a cleanup strategy, your storage grows indefinitely and old artifacts clutter your bucket.

S3 Lifecycle policies let you automate this entirely. You define rules that transition or delete objects based on age, and S3 executes them on your behalf: no scripts, no cron jobs, no manual intervention.

Strategy 1: Archive old versions to Glacier

If compliance or audit requirements mandate that you retain all historical deployment packages, but you rarely need to access them, transition old object versions to a lower-cost storage class:

{
  "Rules": [
    {
      "ID": "ArchiveOldDeploymentPackages",
      "Status": "Enabled",
      "Filter": {
        "Prefix": "deployments/"
      },
      "NoncurrentVersionTransitions": [
        {
          "NoncurrentDays": 30,
          "StorageClass": "GLACIER_FLEXIBLE_RETRIEVAL"
        }
      ]
    }
  ]
}

This rule transitions any non-current object version to S3 Glacier Flexible Retrieval after 30 days. Your active deployment packages remain in S3 Standard for fast access, while historical versions move to archival storage at a fraction of the cost.

For artifacts you need to retain for years but will rarely access again, consider a tiered approach: moving to Glacier Flexible Retrieval first, then to Deep Archive:

"NoncurrentVersionTransitions": [
  {
    "NoncurrentDays": 30,
    "StorageClass": "GLACIER_FLEXIBLE_RETRIEVAL"
  },
  {
    "NoncurrentDays": 365,
    "StorageClass": "DEEP_ARCHIVE"
  }
]

Strategy 2: Delete old versions you no longer need

If you don’t have a compliance requirement to retain every historical artifact, you can expire old versions outright:

{
  "Rules": [
    {
      "ID": "DeleteOldDeploymentPackages",
      "Status": "Enabled",
      "Filter": {
        "Prefix": "deployments/"
      },
      "NoncurrentVersionExpiration": {
        "NoncurrentDays": 14,
        "NewerNoncurrentVersions": 2
      }
    }
  ]
}

This rule keeps the 2 most recent non-current versions of each object (giving you a rollback path) and deletes anything older than 14 days beyond that. This aligns well with a deployment strategy where you want the ability to quickly roll back to your previous one or two releases, but don’t need to retain anything older.

Diagram showing the relationship between S3 object versions and Lambda function versions

Tracking object and function versions

With REFERENCE mode, there is a direct relationship between your S3 object version and your Lambda function version. We recommend the following practices:

  • Tag your objects with metadata from your CI/CD pipeline (commit SHA, build ID, pipeline run ID) so you can trace any deployed function back to the exact source that produced it.
  • Document the mapping between Lambda function versions (or aliases) and S3 object version IDs. This makes rollbacks straightforward: update the function to reference the previous object version.

Cross-account considerations

How you organize your artifact buckets across AWS accounts depends on your operational model:

  • Centralized artifact account: A single bucket in a shared-services or tooling account, with bucket policies granting cross-account s3:GetObject access to Lambda execution roles in workload accounts. This gives your platform team a single inventory of all deployment artifacts with consistent lifecycle, encryption, and access policies.
  • Per-account buckets: Each workload account owns its own artifact bucket. Requires less effort to set up, but harder to enforce consistent governance across many accounts.

Either pattern works with self-managed storage. Choose based on how your organization balances centralized control against team autonomy.

Cross-Region considerations

With REFERENCE mode, your S3 object is the authoritative copy for your function. Self-managed code storage supports cross-Region function creation within a partition for all default Regions (non-opt-in Regions). You can store your code packages in one Region and deploy your functions in another. This makes cross-Region planning critical. There are four factors to balance:

Disaster recovery

This is the most critical consideration. Because your S3 object is the single source of truth in REFERENCE mode, you do not want all your deployment artifacts in a single Region with no fallback. A recommended pattern:

  1. Primary Region: Your main artifact bucket where CI/CD pipelines deposit new deployment packages.
  2. Fallback Region: A secondary bucket populated via S3 Cross-Region Replication (CRR). If your primary Region becomes unavailable, you can update your Lambda functions to reference the replicated objects in the fallback Region.

Enable S3 Replication Time Control (RTC) if you need a guaranteed SLA (15 minutes) for replication completion.

Cost

Weigh replication + storage costs against per-deploy cross-Region data transfer. If you deploy frequently, storing replicated copies in each target Region is usually cheaper. For infrequent deployments, a one-time transfer may suffice.

Governance and data residency

Some organizations, particularly in regulated industries, have strict requirements about where code artifacts can reside. Before configuring cross-Region replication, confirm that your data is permitted to leave its current Region. Certain regulatory frameworks (for example, data sovereignty laws, FedRAMP boundaries) may restrict replication to specific Region pairs.

Performance

If your workload requires fast function creation and activation times, for example, in a CI/CD pipeline where deployment speed is critical, keep your S3 objects in the same Region where you are creating your Lambda functions. Cross-Region reads add latency to the initial code download, which directly impacts how quickly a new function version becomes active after deployment.

For workloads where creation speed is less critical (for example, batch processing functions that are updated infrequently), the latency of a cross-Region read might be acceptable and can simplify your architecture.

Things to know

Before adopting self-managed S3 buckets for your Lambda functions, keep the following in mind:

  • Availability: You can use this feature today in all AWS standard regions where Lambda is supported.
  • Pricing: There is no additional Lambda charge. You pay standard S3 costs for storage, and any cross-Region data transfer.
  • Maximum deployment package size: The existing limits apply: 250 MB unzipped.
  • Supported runtimes: All Lambda runtimes that support .zip deployment packages are compatible. Container image deployments are not affected by this feature.
  • Migration: You can switch an existing function from service-managed to self-managed storage by calling UpdateFunctionCode with the --s3-object-storage-mode REFERENCE parameter. Lambda recreates the function by referencing the object in your S3 bucket and deletes the saved copy.
  • Reverting: You can switch back to service-managed storage at any time by updating the function with --s3-object-storage-mode COPY. Lambda resumes copying the artifact to its internal bucket.
  • Object availability is your responsibility: In REFERENCE mode, Lambda depends on your S3 object being accessible. If the object is deleted, the bucket policy changes, or the KMS key is disabled, new invocations requiring a cold start will fail.

Conclusion

In this post, we showed how self-managed S3 buckets for Lambda give you more capacity, more control, and simpler compliance, all without changing how you write or invoke your functions. Your deployment packages no longer count against account quotas, your security team can apply the same policies to code artifacts that they apply everywhere else, and your disaster recovery story is as strong as the replication capabilities of S3.

To get started:
Protecting Privacy in an AI Era

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/protecting-privacy-in-an-ai-era.html

Daniel Solove argues in the Wall Street Journal (alternate link) that giving people control of their personal data is not an effective way to regulate privacy in this era. Instead, we need to hold companies accountable for their actions, similar to what we do with food and drug companies. Measures such as rigorous data minimization, fiduciary duties, liability for negligent or reckless technological design, liability for algorithms that cause harm, and multi-stakeholder review of technologies will be far more effective.

Paper.

A Video Screen That Is Also a Camera

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/a-video-screen-that-is-also-a-camera.html

Amazing:

Researchers from ETH Zurich in Switzerland, however, managed to create a new type of pixel that can simultaneously do both. This hypercharged pixel, called a Fourier pixel, can generate and sense arbitrary light fields and tap into a pixel’s full potential for carrying information by manipulating light’s intensity, oscillation phases, and polarization. The team reported its findings in a paper published yesterday in Nature.

We are one step closer to 1984 technology:

The telescreen received and transmitted simultaneously. Any sound that Winston made, above the level of a very low whisper, would be picked up by it; moreover, so long as he remained within the field of vision which the metal plaque commanded, he could be seen as well as heard. There was of course no way of knowing whether you were being watched at any given moment.

Paper.

Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/upcoming-speaking-engagements-58.html

This is a current list of where and when I am scheduled to speak:

  • I’m speaking (virtually) at the Policy-Relevant Privacy Research Workshop in Calgary, Canada, on Monday, July 20, 2026.
  • I’m speaking at Boston Leadership Exchange in Boston, Massachusetts, USA, on Wednesday, July 22, 2026.
  • I’m speaking at Cognitive Security Conference in Las Vegas, Nevada, USA. The conference runs August 6-7, 2026; my speaking time is TBD.
  • I’m speaking at DEF CON 34 in Las Vegas, Nevada, USA. The conventions runs August 6-9, 2026; my speaking time is TBD.
  • I’m speaking at LAcon V in Anaheim, California, USA. The convention runs August 27-31, 2026, and my speaking time is TBD.
  • I’m speaking at CanSecWest 2026 in Vancouver, Canada. The conference runs September 30–October 1, 2026; the time of my talk is TBD.

The list is maintained on this page.

Automated Incident Remediation with AWS DevOps Agent and Kiro CLI

Post Syndicated from Jishnu Dasgupta original https://aws.amazon.com/blogs/devops/automated-incident-remediation-with-aws-devops-agent-and-kiro-cli/

Introduction

Automated incident remediation – turning investigation findings into deployed fixes without manual toil – is the next frontier for operations teams running distributed workloads on AWS. Today, when an incident fires at 2 AM, the on-call engineer must correlate telemetry across Amazon CloudWatch, deployment pipelines, and application logs, then manually write and deploy a fix – a process that routinely takes hours. AWS DevOps Agent addresses the first half by autonomously investigating incidents, identifying root causes, and generating mitigation plans in minutes. During preview, customers and partners reported up to 75% lower MTTR, 80% faster investigations, and 94% root cause accuracy.

But investigation and mitigation recommendations are only half the story. Someone still has to read the findings, write the fix, test it, and deploy it. What if that second half could be automated too?

In a previous post, Leverage Agentic AI for Autonomous Incident Response with AWS DevOps Agent, we demonstrated how to configure AWS DevOps Agent to monitor your applications, trigger autonomous investigations, and follow best practices for production deployments. We also published this code sample which demonstrates how investigations could be wired to be triggered automatically when a Amazon CloudWatch alarm is raised. These two articles now allow you to trigger AWS DevOps Agent investigation on a Amazon CloudWatch alarm and produce a mitigation plan.

In this post, we demonstrate how to integrate AWS DevOps Agent mitigation plan output with Kiro CLI – running in headless mode on AWS CodeBuild – to close the remediation loop end-to-end. When AWS DevOps Agent completes a mitigation analysis, an event-driven pipeline automatically routes the findings to Kiro CLI, which applies the fix to your codebase, creates a pull request for human review, and triggers deployment upon approval. The result: L1/L2 incidents go from detection to deployed fix with minimal manual intervention – the only human touchpoint is the pull request approval.

We walk through the complete solution using a sample CloudFormation application, including the infrastructure code, anomaly generation scripts, event routing, and the Kiro CLI steering configuration that makes it all work. All source code is available in the accompanying aws-samples repository.

Solution Overview

Consider a typical web application running on AWS — a frontend behind an Application Load Balancer, backend compute on Amazon EC2, and an Amazon RDS database, with source code and CloudFormation templates in AWS CodeCommit. When something goes wrong in this environment, the solution chains two AWS frontier agents —AWS DevOps Agent for autonomous investigation and mitigation, and Kiro CLI for automated code remediation — through a fully serverless event-driven bridge to take the application from incident to deployed fix.

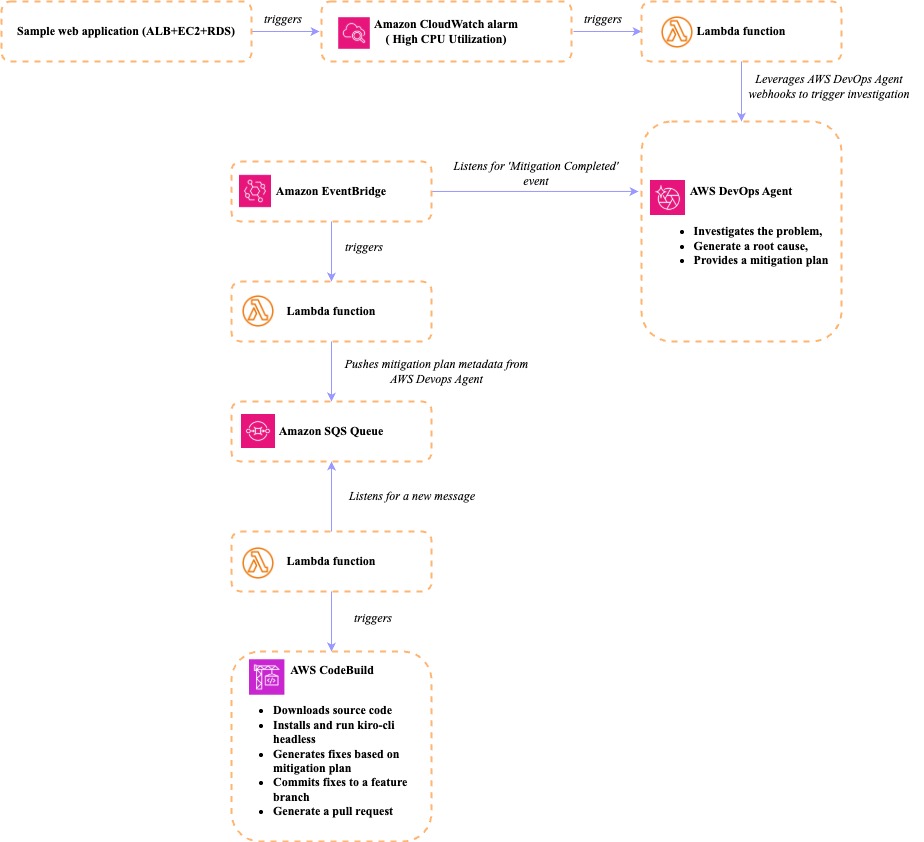
Solution Architecture

Fig 1 – Solution architecture

How it works

  1. An incident occurs – Your application experiences an issue – high CPU utilization, elevated error rates, slow response times. Amazon CloudWatch alarms fire.
  2. DevOps Agent investigates – AWS DevOps Agent, which has your application onboarded into an Agent Space, autonomously correlates metrics, logs, and deployment history to identify root cause and generate a mitigation plan.
  3. EventBridge routes the signal – An Amazon EventBridge rule captures Mitigation Completed events (source: aws.aidevops) and invokes a AWS Lambda function.
  4. Lambda extracts and queues – The AWS Lambda function calls the AWS DevOps Agent API to retrieve the mitigation summary and execution plan, then publishes the payload to Amazon SQS queue.
  5. CodeBuild runs Kiro CLI – When a message arrives in the Amazon SQS queue, a AWS Lambda function with an SQS event source mapping triggers a AWS CodeBuild execution, passing the message content as an environment variable. AWS CodeBuild runs Kiro CLI in headless mode (–no-interactive –trust-tools=read,write,grep,shell), using the mitigation payload as a remediation prompt.
  6. Kiro CLI applies the fix – Guided by a steering file that describes the repository structure and remediation conventions, Kiro CLI modifies the CloudFormation template or application code, commits to a feature branch, and creates a pull request.
  7. Human approves, pipeline deploys – A developer reviews the pull request. Upon approval and merge, the associated deployment pipeline gets triggered to execute the change.

Prerequisites

To follow along with this walkthrough, you need:

  • An AWS account for AWS DevOps Agent access
  • An Agent Space configured
  • Kiro CLI with a Pro, Pro+, or Power subscription (required for headless mode API keys)
  • AWS CLI configured with appropriate credentials
  • The sample repository pushed to your account’s AWS CodeCommit repository

Once completed, follow along the Readme file to setup the components which allow you to implement and execute the above architecture. The sections below provide an explanation of the components that have been built to support the architecture.

Capturing mitigation events

AWS DevOps Agent publishes lifecycle events to the Amazon EventBridge default event bus whenever an investigation or mitigation changes state. Each event uses the source aws.aidevops and a detail-type that identifies the specific like Mitigation Completed, Investigation Completed, or Mitigation Failed. The post focuses on a single signal: the moment a mitigation finishes successfully.

EventBridge rule and Lambda extraction

An Amazon EventBridge rule matching the Mitigation Completed detail-type invokes a AWS Lambda function. The event payload contains metadata (agent_space_id, task_id, and execution_id) which allows the AWS Lambda function to call the AWS DevOps Agent and extracts two key objects: the mitigation summary (what action to take and why) and the execution plan (step-by-step instructions). It publishes this structured payload to an Amazon SQS queue for downstream processing.

Headless remediation with Kiro CLI

With mitigation payloads landing in the Amazon SQS queue, we need a compute environment that can check out the application and infrastructure repository, run Kiro CLI agent against the codebase, and push changes back. AWS CodeBuild is a natural fit — it provides on-demand compute, integrates natively with AWS CodeCommit and requires no persistent infrastructure.

Kiro CLI 2.0 introduced headless mode, which allows it to run programmatically in deployment pipelines without an interactive terminal. You authenticate with an API key (stored in AWS Secrets Manager), pass a prompt, and Kiro CLI executes end-to-end — same tools, same agents, same capabilities as the interactive experience.

How CodeBuild orchestrates the fix

When a message arrives in the Amazon SQS queue, a trigger AWS Lambda function starts a AWS CodeBuild execution, passing the Amazon SQS message body as an environment variable. The AWS CodeBuild buildspec follows a straightforward sequence:

  1. Install : Installs Kiro CLI and configures the environment. The KIRO_API_KEY is pulled automatically from AWS Secrets Manager ,never hardcoded.
  2. Generate prompt : A Python script converts the structured mitigation payload into a natural-language remediation prompt. It inspects the content to classify whether the change targets infrastructure (or application code, then generates a focused prompt with the action, reasoning, and specific instructions.
  3. Create feature branch : Checks out a new branch named after the agent space and execution IDs for traceability.
  4. Run Kiro CLI : Invokes Kiro CLI chat –no-interactive –trust-tools=read,write,grep,shell with the generated prompt. The –trust-tools flag auto-approves specific tool categories following least-privilege, since there is no human to confirm.
  5. Validate and commit : Guardrails check the changes: file count limits, protected file detection, Python syntax validation (py_compile), and YAML linting. If all checks pass, the changes are committed and pushed.
  6. Create pull request : Creates an AWS CodeCommit pull request with the mitigation action as the title and the AWS DevOps Agent reasoning in the description.

The steering file

What makes Kiro CLI effective at remediation – rather than just generating generic code – is the steering file. Steering gives Kiro persistent knowledge about your project: repository structure, coding conventions, and decision frameworks.

For this solution, the steering file serves as the guardrails for automated remediation. It defines:

  • Repository structure – Maps each directory to its purpose.
  • Decision framework – Rules for classifying changes as infrastructure vs. application.
  • Scope constraints – Maximum 3 files per remediation, no new files, no new dependencies, no deletions.
  • Protected files – The buildspec, infrastructure pipeline templates, bridge code, and steering files themselves are explicitly off-limits.
  • Fail-safe – If the prompt is ambiguous or Kiro cannot determine what to change, it makes no changes rather than guessing.

This steering file is committed to the repository, so every AWS CodeBuild execution picks it up automatically. It ensures Kiro CLI makes targeted, predictable changes rather than broad refactors.

From pull request to deployment

At this point, the automated pipeline has done its work – Kiro CLI has analyzed the mitigation plan, modified the appropriate files, and created a pull request on a feature branch. The pull request description includes what was changed, why (directly from the AWS DevOps Agent’s reasoning), and the agent space and execution IDs for full traceability back to the original incident.

This is where the human-in-the-loop gate comes in. A developer reviews the pull request -verifying that the change is correct, scoped appropriately, and safe to deploy. This approval step is deliberate: while we trust the agents to investigate, analyze, and propose fixes, a human makes the final deployment decision.

Once the pull request is approved and merged into the main branch, the deployment pipelines implement the approved changes in the target environment.

The entire cycle – from CloudWatch alarm to deployed fix – completes in minutes rather than hours, with the only manual step being the pull request review. For organizations handling high volumes of L1/L2 incidents, this translates directly into reduced operational toil and faster recovery.

Cleanup

To avoid ongoing charges, remove the resources created during this walkthrough. Refer to the Readme for the complete teardown sequence.

Conclusion

In this post, we demonstrated how to integrate AWS DevOps Agent mitigation outputs with [1] Kiro CLI to build a closed-loop incident remediation pipeline. By connecting these two frontiers agents’ operations teams can go from incident detection to deployed fix with a single human touchpoint: the pull request approval.

This approach delivers measurable impact for enterprise operations:

  • Reduced MTTR – L1/L2 incidents that previously required hours of manual investigation and remediation can now resolve in minutes.
  • Improved operator productivity – Engineers shift from reactive firefighting to reviewing and approving targeted, AI-generated fixes.
  • Consistent remediation – Steering files codify your team’s conventions and decision frameworks, ensuring every automated fix follows the same standards regardless of when or how often incidents occur.

Ready to get started? Clone the aws-samples repository for the complete implementation, visit the AWS DevOps Agent documentation to configure your first Agent Space, and explore the Kiro CLI documentation to learn more about steering-file-driven code generation. Have questions or want to share how you’ve adapted this pattern? Leave a comment below or open an issue in the repository

Jishnu Dasgupta

Jishnu Dasgupta

Jishnu Dasgupta is a Senior Solutions Architect at AWS who specializes in manufacturing and automotive domain. His focus areas are building, migrating and modernizing applications on AWS. He leverages his expertise and experience to help AWS customers build optimized, scalable and fit to purpose architecture on AWS.

Chetan Dharma

Chetan Dharma

Chetan Dharma is a Senior AI Solution architect with 20+ years of experience driving technology transformation for large-scale global enterprises. He has worked across investment banking, logistics, automative, and digital native businesses — progressing from hands-on engineering to architecture to advising AI transformation

Eliminating Java cold starts with AWS Lambda Managed Instances

Post Syndicated from Jay Colodner original https://aws.amazon.com/blogs/compute/eliminating-java-cold-starts-with-aws-lambda-managed-instances/

A single cold start can push your Java Lambda function’s response time from milliseconds to seconds, enough to violate your p99 SLA, timeout a downstream service, and page your on-call. The Java Virtual Machine (JVM) performs best in long-running processes. Its Just-In-Time (JIT) compiler progressively optimizes code over thousands of invocations. Standard serverless execution environments recycle before the JVM reaches peak performance. This creates a tradeoff for latency-sensitive applications between cold-start penalties and runtime optimizations. For production services with p99 service level agreement (SLA) requirements, a single 14-second cold start spike can violate response time guarantees. It triggers downstream timeouts and degrades customer experience.

AWS Lambda Managed Instances changes this equation. As a capability of AWS Lambda, Managed Instances runs your functions on managed Amazon Elastic Compute Cloud (Amazon EC2) instances in your account and maintains JVM persistence across invocations. Connection pools, class hierarchies, and heap state persist across thousands of requests. This allows the JIT C2 compiler to complete optimizations like method inlining, escape analysis, and loop unrolling. The result: 18 to 30% better median latency and 3 to 30x better tail latency compared to Standard Lambda, as the benchmarks in this post demonstrate.

This post benchmarks four Java deployment modes across three workload types using 240,000 requests. The modes compared are Standard Lambda, AWS Lambda SnapStart, GraalVM Native Image, and Lambda Managed Instances. The workload types are CPU-bound, I/O + computation, and I/O-bound. This post presents benchmark results demonstrating Managed Instances delivering 30% better median latency and removing multi-second cold-start spikes on CPU-bound work after JIT warmup. It explains why these gains occur, maps each deployment mode to specific traffic patterns and cold-start tolerance requirements, and provides a decision framework for selecting the right approach for your workload.

Benchmarking setup

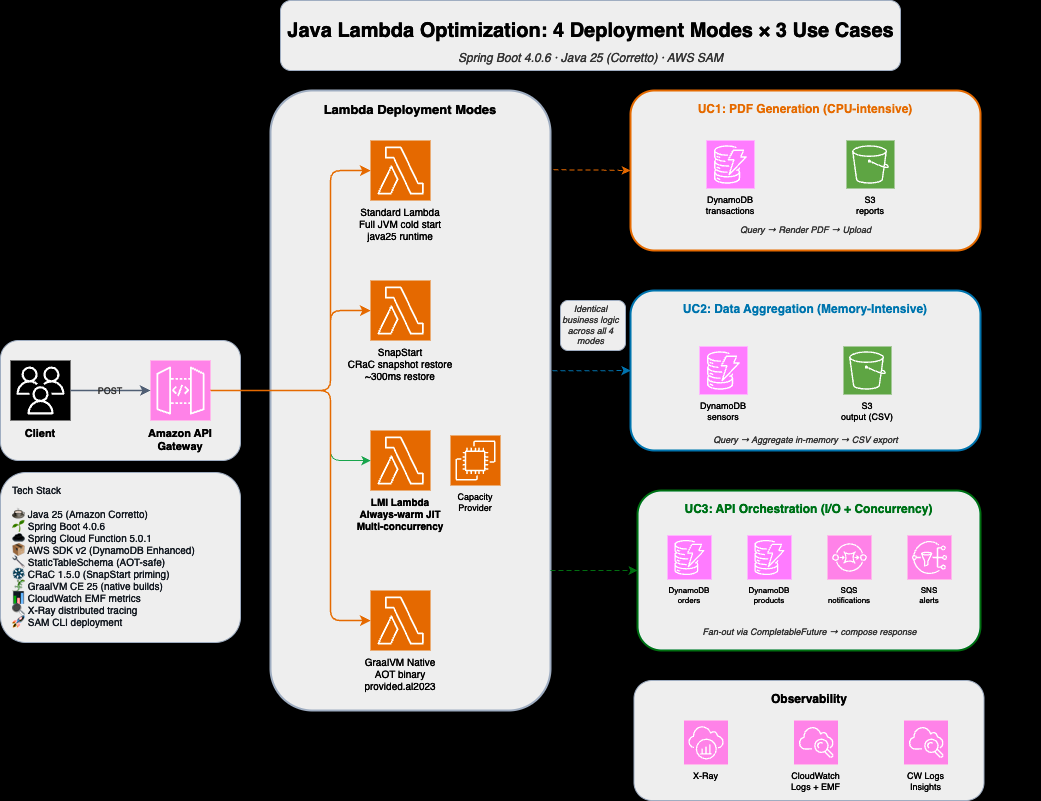
The benchmark runs all four deployment modes with identical Spring Boot 4.0.6 applications on Java 25 and AWS SDK v2. This configuration verifies fair comparison across modes. We tested three workloads: UC1 (PDF generation, CPU-bound), UC2 (data aggregation, I/O + computation), and UC3 (API orchestration, I/O-bound). The benchmark sends 240,000 requests using Artillery load testing at 33 RPS. Standard Lambda, SnapStart, and Native Lambda use 1024 MB (1 vCPU). Managed Instances uses c7i.xlarge instances with 2048 MB memory. Concurrency is tuned per workload (UC1=3, UC2=5, UC3=10) based on load testing to avoid thread contention. The benchmark measures p50, p99, and maximum latency across 10 runs of 2,000 requests each, with 5-minute cool-down between runs. The benchmark tracks JIT compilation metrics via Amazon CloudWatch Embedded Metrics Format. You can validate these results against Amazon API Gateway access logs, which confirm a <0.1% error rate. The GitHub repository contains complete source code, AWS Serverless Application Model (AWS SAM) templates, load scripts, and raw data. Performance claims in this post reference data from this benchmark methodology.

Figure 1 presents the architecture for all four deployment modes running in parallel against shared backend services.

Architecture diagram showing all four Lambda deployment modes (Standard, SnapStart, GraalVM Native, Managed Instances) running in parallel against shared backend services including DynamoDB, S3, SQS, and SNS

To reproduce these benchmarks or deploy the sample applications, refer to the GitHub repository. The repository contains complete SAM templates, Artillery load configurations, deployment instructions, and cleanup commands. This post focuses on benchmark results and analysis. The benchmark used the following tools and services:

Observing max latency

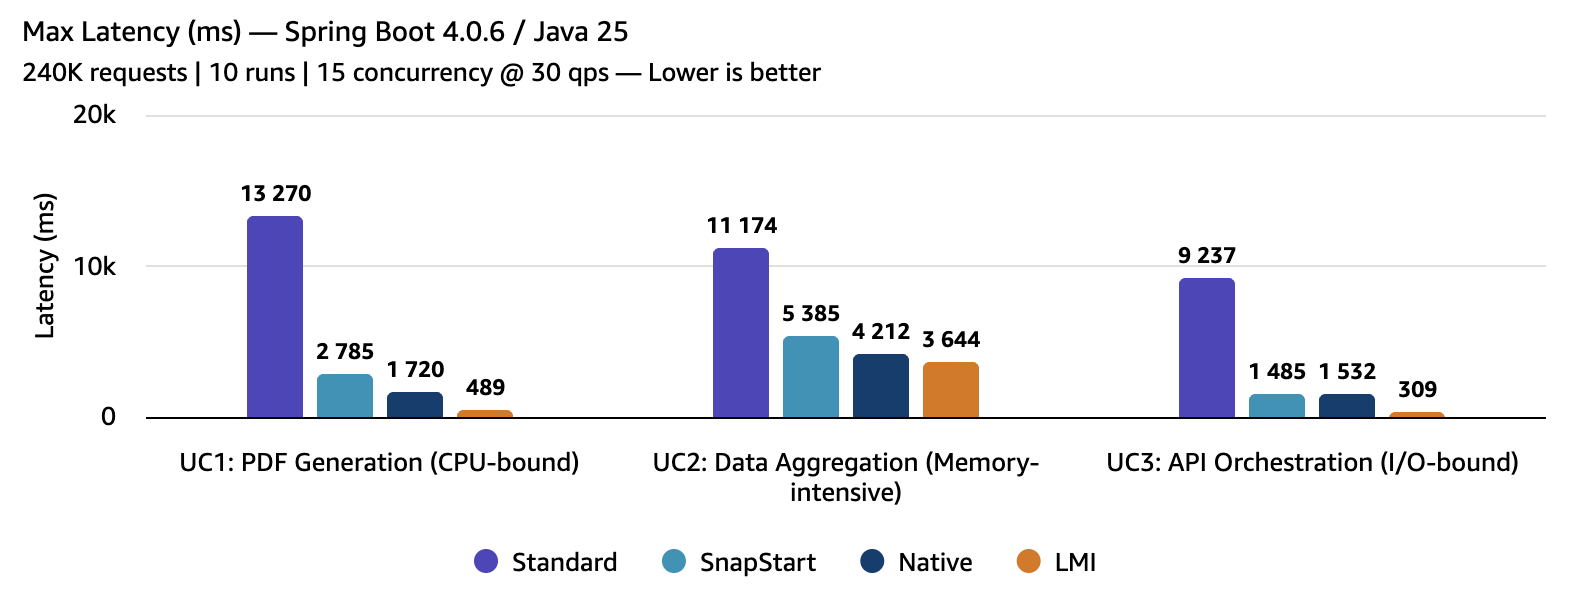
Managed Instances removes the extreme tail spikes characteristic of cold starts. Managed Instances delivers 27x faster maximum latency on CPU-bound workloads (UC1: 489 ms vs. 13,270 ms Standard). Mixed I/O + compute workloads see a 3x improvement (UC2: 3,644 ms vs. 11,174 ms Standard). I/O-bound workloads improve 30x (UC3: 309 ms vs. 9,237 ms Standard). We measured all results using the methodology described in Benchmarking setup.

Bar chart comparing maximum latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

The Standard Lambda 13-second maximum on UC1 represents a full cold start. That cold start includes JVM boot, Spring context initialization, Amazon DynamoDB client setup, and the first PDF render. SnapStart reduces this to under 3 seconds by restoring from a Firecracker microVM snapshot. However, the restore process plus re-initialization of resources that cannot be checkpointed (network connections, random number generators) still adds latency. GraalVM Native starts in under 2 seconds because the ahead-of-time (AOT) compiled binary skips JVM boot entirely. The Managed Instances maximum of 487 ms is not a cold start; it’s the slowest warm request across 20,000 invocations. For production SLAs, a 14-second cold start spike on Standard Lambda violates most requirements, while Managed Instances removes that spike entirely.

Observing median latency (p50)

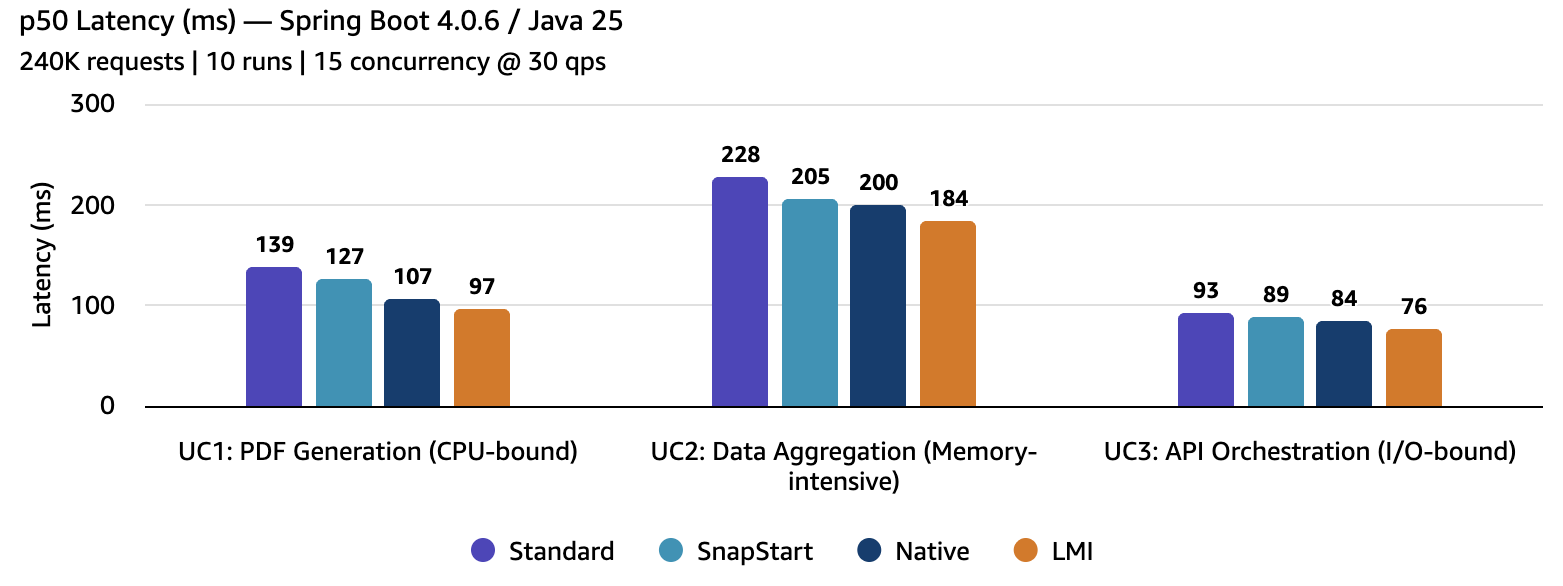
Lambda Managed Instances delivered the lowest median latency across all three workloads. Results demonstrate 30% faster median latency on CPU-bound workloads (UC1: 97 ms vs. 139 ms Standard). Mixed I/O + compute achieves a 19% improvement (UC2: 184 ms vs. 228 ms Standard). I/O-bound workloads improve 18% (UC3: 76 ms vs. 93 ms Standard).

Bar chart comparing median (p50) latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

The improvement scales with CPU intensity because the JIT C2 compiler on persistent Managed Instances optimizes hot code paths that short-lived serverless environments never reach. On CPU-bound workloads (UC1), the JIT compiler has more opportunity to optimize tight loops in PDF rendering. On I/O-bound workloads (UC3), network latency to Amazon DynamoDB, Amazon SQS, and Amazon SNS dominates the request duration, so JIT optimization provides smaller gains.

Observing tail latency (p99)

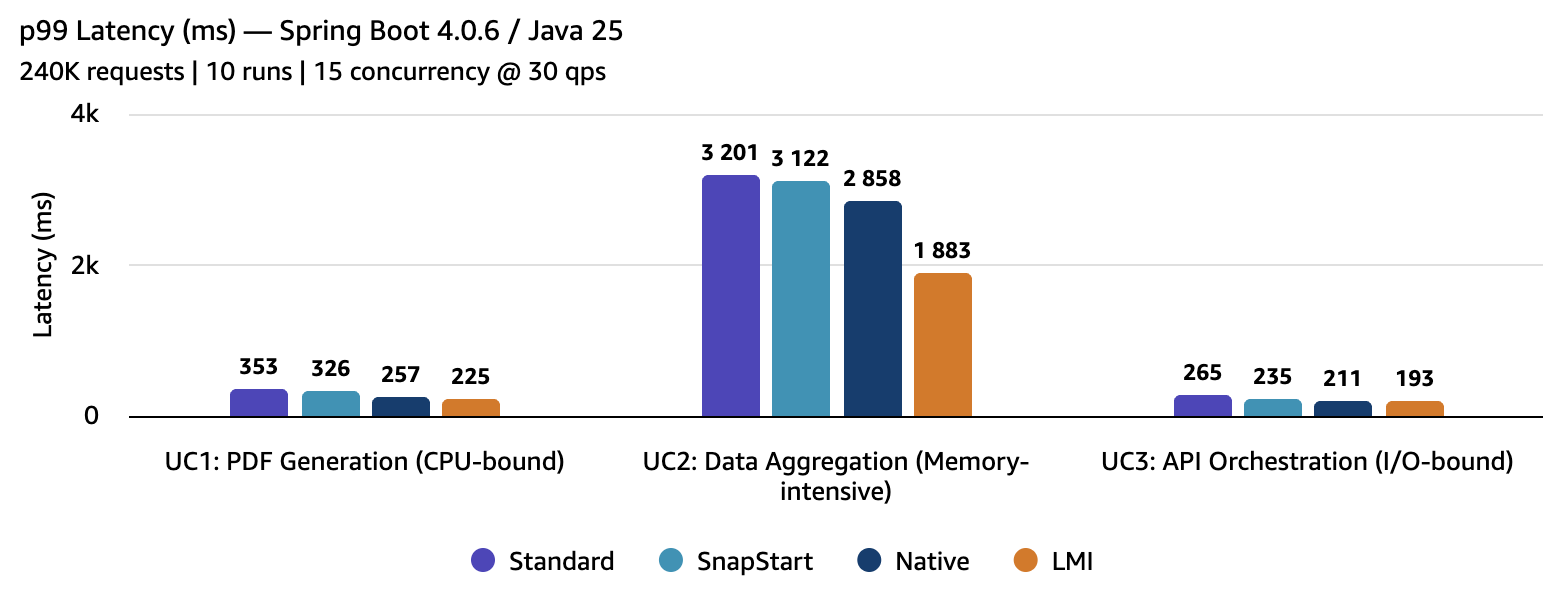
Managed Instances showed even larger improvements at the tail of the latency distribution. The p99 improves 36% on CPU-bound workloads (UC1: 225 ms vs. 353 ms Standard). Mixed I/O + compute achieves a 41% improvement (UC2: 1,883 ms vs. 3,201 ms Standard). I/O-bound workloads improve 27% (UC3: 193 ms vs. 265 ms Standard).

Bar chart comparing p99 tail latency across Standard Lambda, SnapStart, GraalVM Native, and Managed Instances for three workload types

UC2 showed the largest p99 improvement (41%) because data aggregation combines DynamoDB queries, returning hundreds of records with in-memory statistical computation and Amazon S3 uploads. Standard Lambda environments that haven’t fully warmed their JIT produce significantly slower responses at the tail. The persistent JIT optimization (-Xms512m -Xmx1408m) with G1 garbage collection (GC) and explicit heap sizing on Managed Instances both contribute to tighter tail latency distribution. For services with SLAs on p99 response time, this reliability improvement matters more than median performance. For workloads with significant heap pressure, tuning -XX:MaxGCPauseMillis and monitoring GC logs can further tighten tail latency.

Why Lambda Managed Instances is faster: JIT compilation

The JVM’s Just-In-Time compiler works in tiers. The C1 compiler performs initial compilation quickly with basic optimizations. The C2 compiler profiles execution over hundreds of invocations and then applies aggressive optimizations: method inlining (eliminating function call overhead), escape analysis (allocating objects on the stack instead of the heap), loop unrolling (reducing branch overhead), and vectorization (processing multiple data elements in a single CPU instruction).

The following table presents JIT warmup progression using java.lang.management.

CompilationMXBean emitted through Amazon CloudWatch Embedded Metrics Format. We collected this data from a 1,500-request sustained load test on UC1 (PDF generation):

Phase Invocation Avg Latency What’s Happening
First requests (application init) 1 ~2,400ms JVM boot, spring context creation, SDK client setup
Early requests (C1 compiled) 2-100 ~145ms C1 compiler active. App is functional, but not optimized
Steady state (C2 optimized) 1000+ ~38ms C2 optimizations completed

The first invocation includes one-time application start costs: class loading, Spring context initialization, and DynamoDB client construction. These costs are unrelated to JIT compilation and occur on any deployment mode.

Once C1 compilation stabilizes during early invocations, latency reaches approximately 145ms. This is the baseline compiled performance. Over the next several hundred invocations, the C2 compiler profiles hot code paths and applies optimizations. By invocation 1,000, latency drops to 38ms. This represents a 3.8x improvement from JIT optimization alone.

Standard Lambda environments typically recycle before C2 completes its optimization passes. On Managed Instances, concurrent requests share the same JVM. This accelerates JIT profiling: three concurrent requests generate three times the method invocation data for the C2 compiler to optimize. The C2 compiler profiles execution patterns across all concurrent requests. It identifies hot code paths faster and applies optimizations sooner than single-concurrency environments.

What this means: CPU-bound workloads see the largest gains (30% faster median latency on UC1) because the JIT compiler has more opportunity to optimize tight loops and method calls. I/O-bound workloads see smaller gains (18% faster on UC3) because network latency to DynamoDB, SQS, and SNS dominates request duration. The JIT compiler still optimizes your code, but the network time remains constant across all deployment modes.

Choosing the right mode

No single mode wins in every scenario. The right choice depends on your traffic pattern, cold-start tolerance, team expertise, and operational complexity budget.

Lambda Managed Instances is ideal for steady-state traffic patterns above 5 requests per second with low cold-start tolerance (p99 SLA under 500 ms). Best for workloads with predictable, sustained traffic that need low latency with zero cold starts. Managed Instances excels at CPU-bound workloads where JIT optimization compounds.

SnapStart works well for variable traffic patterns where cold-start reduction matters. Choose this as the default for Java Lambda functions. SnapStart reduces cold starts with minimal code changes (add CRaC priming). You have no additional infrastructure to manage. Works with the existing Lambda scaling model.

GraalVM Native Image works well for bursty traffic patterns with strict cold-start tolerance (sub-second cold starts required). Ideal if your team can invest in AOT compatibility (reflection configuration, build pipeline). This mode offers a smaller memory footprint. Requires testing for SDK compatibility.

Standard Lambda is the baseline for low-traffic or burst workloads where cold starts of 6-14 seconds are acceptable. Works well when invocation frequency is low enough that per-request billing is cheaper than fixed instance costs, or when operational simplicity is the top priority.

For example, if you run a Spring Boot API handling 100 requests per second with a 400 ms p99 SLA, Lambda Managed Instances reduces your p99 from 353 ms (cutting it close) to 225 ms (comfortable margin) and removes the multi-second cold start spikes that violate your SLA entirely.

Dimension Standard SnapStart Native Managed Instances
Cold start 6-14 s 2-7 s 800 ms – 2 s None
Warm p50 (CPU-bound) 139 ms 127 ms 107 ms 97 ms
Tail latency Worst Better Good Fastest
Error rate Low Low Higher (SDK compat) Low
Operational complexity Lowest Low High (build pipeline) Medium (VPC, sizing)
Burst scaling Fastest Fastest Fastest Slower (capacity provider)
Migration effort None Low (add CRaC priming) High (AOT compat, reflection configuration) Medium (capacity provider, VPC, thread safety)
Memory efficiency Good Good

Lowest

(125-154 MB)

Fixed per instance

Lambda Managed Instances supports Graviton4 (arm64) instances, which offer approximately 20% better price-performance based on AWS published Graviton4 benchmarks. These benchmarks use x86_64 for consistency across all four modes (GraalVM native cross-compilation to arm64 adds complexity). The arm64 parallelization characteristics could shift the performance curves for longer-lived deployment modes like Managed Instances in ways worth exploring in a future post.

Cost considerations

Lambda Managed Instances uses instance-based pricing rather than per-invocation billing. For steady-state workloads above approximately 9 requests per second, the fixed instance cost is lower than equivalent Standard Lambda GB-second charges. You can use the official pricing calculator to compare Managed Instances and standard Lambda costs.

Try it with your runtime version

These benchmarks use Java 25 with Spring Boot 4.0.6. The GitHub repository also includes configurations for Java 21 with Spring Boot 3.x. The repository README walks you through deployment, load testing, and collecting your own metrics.

Conclusion

This post demonstrates how Lambda Managed Instances solves a fundamental Java-on-serverless mismatch. The JVM’s JIT compiler needs time to optimize hot code paths. Standard Lambda recycles environments before the JVM reaches peak optimization. Managed Instances keeps the JVM alive across invocations, allowing the C2 compiler to reach peak optimization. The benchmarks show the impact. In these benchmarks, Managed Instances delivered 18 to 30% faster p50 latency than Standard Lambda. Tail latency improved 27 to 41% at p99. Maximum response times dropped 3 to 30x on CPU-bound workloads. The 3.8x improvement from JIT optimization alone shows what’s possible when the runtime has time to complete its work.

For more information, refer to the Lambda Managed Instances documentation. The GitHub repository contains the complete benchmark code, SAM templates, and deployment instructions. Share your results in the comments and let the community know how Managed Instances performs on your workloads. To delete all benchmark resources and avoid ongoing charges, run the cleanup commands documented in the GitHub repository README.

AI Data Centers and the Concentration of Wealth

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/ai-data-centers-and-the-concentration-of-wealth.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

Opposition to AI data centers has emerged as a primary theme in US politics, one that—surprisingly—doesn’t fall along party lines. We applaud people coming together for constructive debate on any issue, and agree that communities need to evaluate whether any economic benefits these data centers bring is worth their costs. Still, we worry that a focus on data centers obscures the larger impacts of AI on people’s lives: the concentration of power of AI companies, and their widespread political and financial influence.

Local data center opposition is grounded in legitimate concerns about misallocation of land resources when housing is at a premium, pressures on already higher energy prices, and localized environmental impact. Unlike other resource-consuming and polluting industrial facilities, data centers produce very few jobs. The fact that US opposition to data centers seems to be most fierce among lower-income communities reflects righteous indignation with an inequitable bargain, where tech companies and developers profit from exploiting local resources but offer little in return. On a global scale, their carbon footprint could grow unsustainably if usage accelerates. And all this is in aid of a technology that many fear will propagate misinformation, take their jobs, or even cause existential risks for humanity.

For some, data center opposition may feel like the only tangible mechanism for registering their concern, disapproval, or even anger about AI. The problem is that this may be exactly what the AI companies are banking on. They can overcome the protest when it matters to them, and live with a significant fraction of proposals being defeated. More importantly, focusing political opponents on the data center issue obscures the bigger prize they’re after.

While there is a staggering three-quarters of a trillion dollars being spent on data center infrastructure by US companies this year alone, this investment should be taken in perspective. The market for enterprise software, for example, is about twice this size. And it’s small compared with what these companies actually want.

AI companies have their eyes set on capturing all the value created by entire industries. The technology has arguably already conquered customer service and consumer sales. But on the horizon are bigger targets, such as enterprise software development, creative design, management and even legal services. In AI companies and their allies’ vision of the future, AI replaces teachers and doctors. The companies would rather spend time fighting resistance to how fast they are building computing infrastructure than dealing with issues of how their products should be used in those fields, or how those fields should be protected from their products.

And while data center opposition campaigns have been successful in building widespread appeal, their effectiveness in the US is mixed. They seem to be most successful when organizing against speculative, early-stage data center proposals that have a relatively low likelihood to ever see fruition. Meanwhile, advanced-stage, well-capitalized data center projects have proven to have the resources to overcome local opposition. An OpenAI- and Oracle-backed facility in Saline township, Michigan, is breaking ground on construction even after local officials voted to reject it. The developers sued the town of 3,000 and forced a settlement that involved their project going forward. Meanwhile, the Trump administration, a vigorous ally of corporate AI, has signaled its willingness to advance AI infrastructure development by overriding state objections and even using federal lands.

Also consider that rampant data center development may be a momentary spike rather than a longstanding concern. Demand for the centralized computing that data centers provide may well decline over time. The leading Chinese labs, such as Z.ai, are innovating in technical mechanisms to make frontier-class models smaller and cheaper to run. AI power users have become adept at miniaturizing open weight models, ones published free for anyone to download and use, to run locally on their own computers. Apple and Google both support infrastructure stacks for running AI models directly on mobile phones. It could be that the current mania for data centers will look like the fiber optic cable bubble from the early 2000s, as demand shifts to smaller models and AI usage on people’s own devices.

For those concerned primarily with affordability and environmental protection, singling out data center construction is misplaced. Energy rates and inflation today seem to be most visibly affected by the US-Iran war. The US is disinvesting in long-term energy security by ceding the renewable energy industry to China and actively cancelling climate commitments. Consider that 10% of global carbon emissions stem from heating buildings, which dwarfs energy use by AI and could be cut fivefold by using heat pumps powered by renewable energy. With respect to housing affordability, federal housing subsidies have changed little over three decades, in inflation-adjusted terms, even as housing costs have spiked and homeowners have enjoyed robust tax incentives.

As for AI itself, the concentration of power and wealth in these tech companies is the greatest existential risk facing society today. This means we must limit corporate power, especially corporations’ ability to exploit the public and manipulate our political system.

Opposing data centers should be just a starting point. We can advocate for states to regulate AI, to reject irresponsible uses of the technology, and shape corporate behavior. We can fight for AI computation to be taxed, so that the public can capture some of the profit of AI use while also forcing AI companies to internalize more of the energy and environmental consequences associated with its use. And we all can join the global movement for Public AI, an alternative ecosystem for AI that is developed under public control with an incentive structure to create public benefit rather than private profit.

The US midterm elections present ample opportunity for those seeking to control the AI political agenda. In the recent New York congressional Democratic primary, PACs linked to the dueling AI companies Anthropic and OpenAI spent millions of dollars lobbying for or against “AI safety“, the idea that we must urgently monitor and prevent people from using AI to cause catastrophic harms. We’re already seeing a similar dynamic play out in races in Massachusetts and other states.

Why would Anthropic and OpenAI—bitter industry rivals but fundamentally on the same side politically—support opposing viewpoints? Because they both ultimately profit from the mystique: the idea that their products are so powerful that controlling those products is the world’s most important challenge. Here’s the typical read on the dynamic. To one side (backed by OpenAI affiliates), “safety” comes from the appearance of US industry dominating AI innovation, under the slow-moving control of federal lawmakers (and without pesky state regulators in the way). To the other side (backed by Anthropic), “safety” means a heavier regulatory framework that plays to Anthropic’s posturing as the ethics- and compliance-focused AI vendor. In both cases, it’s more marketing than principled concern about safety.

Political organizers should call out and reject the AI companies’ framing of the debate, and reorient campaign agendas around populist resistance to corporate concentration of wealth and power. When AI companies pump millions into legislative races, the result should not be hyperbolic discussion of AI superintelligence. And when a plot of land in a small town is pitched as a data center site, the debate should be about more than the local costs and benefits. It should include out-of-control money in politics, and Citizens United-proof solutions to limit corporate influence like public financing and state regulation.

We all have a vested interest in what’s on the policy agenda, and what the outcomes are. Today, the greatest risk AI poses to society is the exacerbation of inequality and the concentration of wealth. The real problem is trillion-dollar AI companies and their trillionaire oligarchs cozying up to political power in Washington and governments worldwide, and using their money to enact their agenda over the popular will of the people. This is the issue we’d like to see put front and center, and it requires solutions much more extensive than slowing data center development.

Friday Squid Blogging: “Squidbleed” Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/friday-squid-blogging-squidbleed-vulnerability.html

In a rare combined cybersecurity/squid post, a twenty-nine-year-old squid proxy bug can leak HTTP requests.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Blog moderation policy.

Announcing Lambda MicroVMs: serverless compute environments with VM-level isolation and near-instant startup

Post Syndicated from Ayush Kulkarni original https://aws.amazon.com/blogs/compute/announcing-lambda-microvms-serverless-compute-environments-with-vm-level-isolation-and-near-instant-startup/

We recently announced the launch of AWS Lambda MicroVMs, a new serverless compute primitive that provides VM-level isolation, near-instant startup performance, and state retention. You can now give each user or job their own execution environment to securely run just-in-time code – either user or AI generated – without managing virtualization infrastructure or choosing between isolation, speed, and state retention. Lambda MicroVMs are powered by Firecracker virtualization, the technology underpinning AWS Lambda. You can use Lambda MicroVMs to build data analytics applications, AI sandboxes, vulnerability scanners, and interactive development environments.

Evolution of serverless compute

When we launched AWS Lambda in 2014, the premise was simple: give developers a way to run code without thinking about servers. Upload a handler, configure a trigger, and let the service handle infrastructure provisioning, scaling, patching, and availability. Over the past decade, Lambda has grown to process tens of trillions of requests each month for over 1.5 million customers. Under the hood, those invocations run inside a Lambda-managed Firecracker microVM – a lightweight virtual machine that combines hardware-level virtualization and near-instant startup speed. With Lambda SnapStart, we used Firecracker’s snapshotting capabilities to accelerate startup times by resuming execution environments from pre-initialized snapshots (carrying memory and disk state) rather than cold-booting them.

Today, a growing class of applications need to run code supplied by users or AI agents just-in-time – and need Firecracker’s core capabilities directly: hardware isolation, near-instant startup, and state retention over extended periods. Achieving this today often requires building custom infrastructure that diverts teams from core application development. We’ve been hearing this theme from customers across use cases and industry verticals:

  • Interactive code environments like browser-based IDEs, notebooks, and vibe-coding platforms need to deploy and execute user-generated code in per-user environments that start within seconds and retain state – like installed packages, generated files, and running processes – across interactions.
  • Data analytics platforms run user-supplied or LLM-generated queries and notebooks in isolated environments that retain large working sets over long durations – such as an 8-hour workday – with the ability to resume quickly after periods of inactivity.
  • AI coding assistants and agents run LLM-generated code iteratively, while retaining context between iterations, and rapidly launching and shutting down environments to evaluate alternative code paths, such as for reinforcement learning.
  • IT security scanners execute vulnerability assessments in compute environments that are strongly isolated from one another, can scale to handle bursts of concurrent scan requests, and support elevated operating system privileges.
  • CI/CD platforms need ephemeral, isolated build and test environments that start quickly and can be discarded after each run.

Introducing Lambda MicroVMs

Now, with AWS Lambda MicroVMs, developers can directly use the isolation, speed, and state snapshotting of Firecracker MicroVM as a primitive, while keeping the serverless simplicity of AWS Lambda. Lambda MicroVMs provide these key capabilities.

  1. Snapshot-based, near-instant startup: To optimize startup speed, MicroVMs are launched from MicroVM images, which are pre-initialized Firecracker snapshots of your application’s memory and disk state. When you create a MicroVM image, the service executes your Dockerfile, initializes your application, and snapshots the MicroVM. Lambda starts MicroVMs from this snapshot with your dependencies loaded.
  2. Direct HTTPS connectivity: Each MicroVM exposes a dedicated HTTPS endpoint for inbound connectivity to individual ports. You can connect to applications running within your MicroVM using standard HTTPS clients, WebSocket connections, or gRPC – exactly as you would with a container or VM.
  3. Lifecycle control with state retention: Lambda MicroVMs allow you to control the lifecycle of each execution environment, enabling you to support interactions that last a few minutes to sessions that span 8 hours.
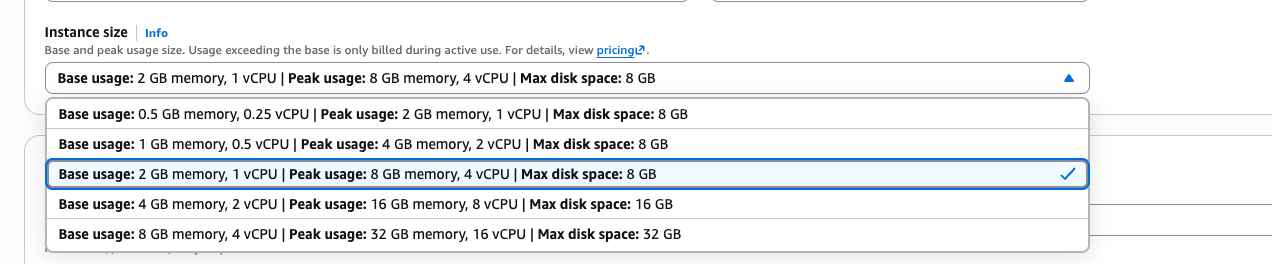
  4. Vertical and horizontal scaling: Each MicroVM starts with a configurable baseline — 2 GB memory and 1 vCPU by default (up to 8 GB and 4 vCPUs), with CPU allocated in a 2:1 ratio to memory. From that baseline, MicroVMs scale vertically by up to 4x automatically, meeting peak resource demands for each user or session without any action on your part. MicroVMs also scale horizontally — you can launch several hundred within a minute during traffic spikes. For details on service limits, refer to Lambda service quotas.
  5. Internet and VPC access: By default, Lambda MicroVMs support outbound connectivity to the public internet without additional configuration. For private VPC connectivity to resources such as databases or internal APIs, you can use a Lambda Network Connector (LNC). LNC is a new Lambda resource that provides managed, configurable network connectivity between your MicroVMs and your private VPC.

Building with Lambda MicroVMs

Lambda MicroVMs introduces two core resource types: a MicroVM image – a versioned artifact containing your runtime environment and application code, and MicroVMs – individual instances launched on demand from a MicroVM image.

Let’s make this concrete with an example. You are a cloud architect building a data analytics application which under the hood, manages compute environments to generate insights for data analysts within your organization. Analysts load multi-gigabyte datasets and generate visualizations in sessions that last hours with idle gaps when they switch to other tasks. When analysts return, they expect to pick up exactly where they left off. Here’s how you can use MicroVMs for this workload:

Step 1: Define your environment

Write a Dockerfile that installs your data science stack. This runs once at MicroVM image build time – every analyst’s MicroVM starts with these dependencies already loaded. This Dockerfile builds a notebook server that accepts code execution requests, runs them in-process (so state accumulates across requests), and returns results. Your customer-facing UI calls this notebook server for each analyst.

FROM public.ecr.aws/lambda/microvms:al2023-minimal

# Install Python 3.12 and pip
RUN dnf install -y python3.12 python3.12-pip && dnf clean all

RUN pip3.12 install --no-cache-dir \
    pandas numpy scipy scikit-learn matplotlib seaborn \
    fastapi uvicorn boto3 pyarrow

COPY notebook_server.py /app/notebook_server.py
WORKDIR /app
EXPOSE 8080

CMD ["python3.12", "notebook_server.py"]

Next, package and upload your application artifacts and Dockerfile to S3.

zip -r notebook-env.zip Dockerfile notebook_server.py
aws s3 cp notebook-env.zip s3://amzn-s3-demo-analytics-platform/artifacts/notebook-env.zip --region us-east-1

With these in place, create a MicroVM image:

aws lambda-microvms create-microvm-image \
    --name analytics-notebook \
    --code-artifact '{"uri": "s3://amzn-s3-demo-analytics-platform/artifacts/notebook-env.zip"}' \
    --base-image-arn arn:aws:lambda:us-east-1:aws:microvm-image:al2023-1 \
    --build-role-arn arn:aws:iam::123456789012:role/NotebookBuildRole \
    --resources '[{"minimumMemoryInMiB": 4096}]' \
    --region us-east-1

When you create a MicroVM image, Lambda executes your Dockerfile, starts your application, and takes a Firecracker snapshot of the fully initialized environment with the libraries imported, and notebook server listening. Every MicroVM launched from this image skips this initialization step, and provides near-instant startup.

Step 2: Launch a MicroVM when an analyst starts their session

Once your MicroVM image is ready, you can start a new MicroVM for each analyst session. The idle policy encodes your business logic: auto-suspend after 5 minutes of inactivity, retain the suspended state for up to 8 hours (covers a full workday), and auto-resume when the analyst’s next request arrives. Within seconds, the analyst has a dedicated environment with their own filesystem, and a dedicated HTTPS endpoint.

aws lambda-microvms run-microvm \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --image-version 1.0 \
    --idle-policy '{"maxIdleDurationSeconds":300,"suspendedDurationSeconds":28800,"autoResumeEnabled":true}' \
    --maximum-duration-in-seconds 28800 \
    --execution-role-arn arn:aws:iam::123456789012:role/notebook-exec-role \
    --region us-east-1

# MicroVM endpoint url is returned by the run-microvm API call
ENDPOINT="https://a1b2c3d4-e5f6-7890-abcd-1234567890ef.lambda-microvm.us-east-1.on.aws"

When a data analyst submits a query, it is submitted as an HTTPS request to their assigned MicroVM. You can test this using curl on the MicroVM endpoint.

curl -X POST "$ENDPOINT/execute" \
    -H "X-aws-proxy-auth: $TOKEN" \
    -H "Content-Type: application/json" \
    -d '{"code": "import pandas as pd; df = pd.read_parquet(\"s3://amzn-s3-demo-data-lake/transactions.parquet\"); print(f\"Loaded {len(df)} rows, {df.memory_usage(deep=True).sum()/1e9:.1f} GB\")"}'

Notice that you can separate the build-time IAM role from the execution-time IAM role for finer-grained control over each tenant’s permissions.

Step 3: Suspend and resume during idle periods

After 5 minutes of inactivity, the MicroVM is automatically suspended based on the configured idle policy. When the MicroVM is suspended, its memory and disk state is preserved.

Two hours later, the analyst returns and sends the next query. The MicroVM auto-resumes within seconds. The memory and disk state are restored exactly as the analyst left them – no re-computation or re-loading required.

Analysts can also suspend and resume their MicroVMs directly using the APIs.

aws lambda-microvms suspend-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

aws lambda-microvms resume-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

Step 4: Connect to private data sources

If your data lives in a private VPC, for example, Amazon Redshift clusters or RDS databases, you can use a Lambda Network Connector (LNC) to give your analysts MicroVMs access to this data. Create a network connector once:

aws lambda-core create-network-connector \
    --name analytics-vpc \
    --configuration '{"VpcEgressConfiguration":{"SubnetIds":["subnet-data1","subnet-data2"],"SecurityGroupIds":["sg-analytics"],"NetworkProtocol":"IPv4","AssociatedComputeResourceTypes":["MicroVm"]}}' \
    --operator-role arn:aws:iam::123456789012:role/ConnectorRole \
    --region us-east-1

Then, reference it when starting a MicroVM. Re-use network connectors across all MicroVMs that share the same network configuration.

aws lambda-microvms run-microvm \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --egress-network-connectors '["arn:aws:lambda:us-east-1:123456789012:network-connector:analytics-vpc"]' \
    --idle-policy '{"maxIdleDurationSeconds":300,"suspendedDurationSeconds":28800,"autoResumeEnabled":true}' \
    --region us-east-1

Now, your organization’s analysts can query private databases directly from their notebook environment.

Step 5: Cleaning up

To stop incurring charges, terminate any running MicroVMs and delete unused resources.

# Terminate the MicroVM
aws lambda-microvms terminate-microvm \
    --microvm-identifier microvm-a1b2c3d4-e5f6-7890-abcd-1234567890ef \
    --region us-east-1

# Delete the network connector (if created)
aws lambda-core delete-network-connector \
    --identifier analytics-vpc \
    --region us-east-1

# Delete the MicroVM image
aws lambda-microvms delete-microvm-image \
    --image-identifier arn:aws:lambda:us-east-1:123456789012:microvm-image:analytics-notebook \
    --region us-east-1

To recap, with MicroVMs we build an image once, launch isolated MicroVMs per user or job, interact over HTTPS, suspend when idle, and terminate when done. This pattern applies broadly, across use cases. For instance, an IT security platform scanning customer repositories has similar requirements: an isolated environment per scan, the ability to run with elevated operating system privileges, and rapid horizontal scaling to hundreds of concurrent scans. Similarly, an AI coding assistant needs per-developer sandboxes that retain installed packages and generated files across iterative code-write-test cycles, with suspend/resume preserving context when developers switch tasks. In each case, the workflow is the same.

Building MicroVMs with Agent Toolkit for AWS

In the previous section, we demonstrated Lambda MicroVMs core API operations. You can also use your preferred Agentic development tools to start developing with Lambda MicroVMs. Simply install the AWS Lambda MicroVMs skill from the Lambda MicroVMs console, or use the Agent Toolkit for AWS.

To get started in the AWS Lambda console, choose the highlighted button to access the MicroVMs agent instructions as in Figure 1:

Figure 1: Access MicroVM agent instructions

Figure 1: Access MicroVM agent instructions

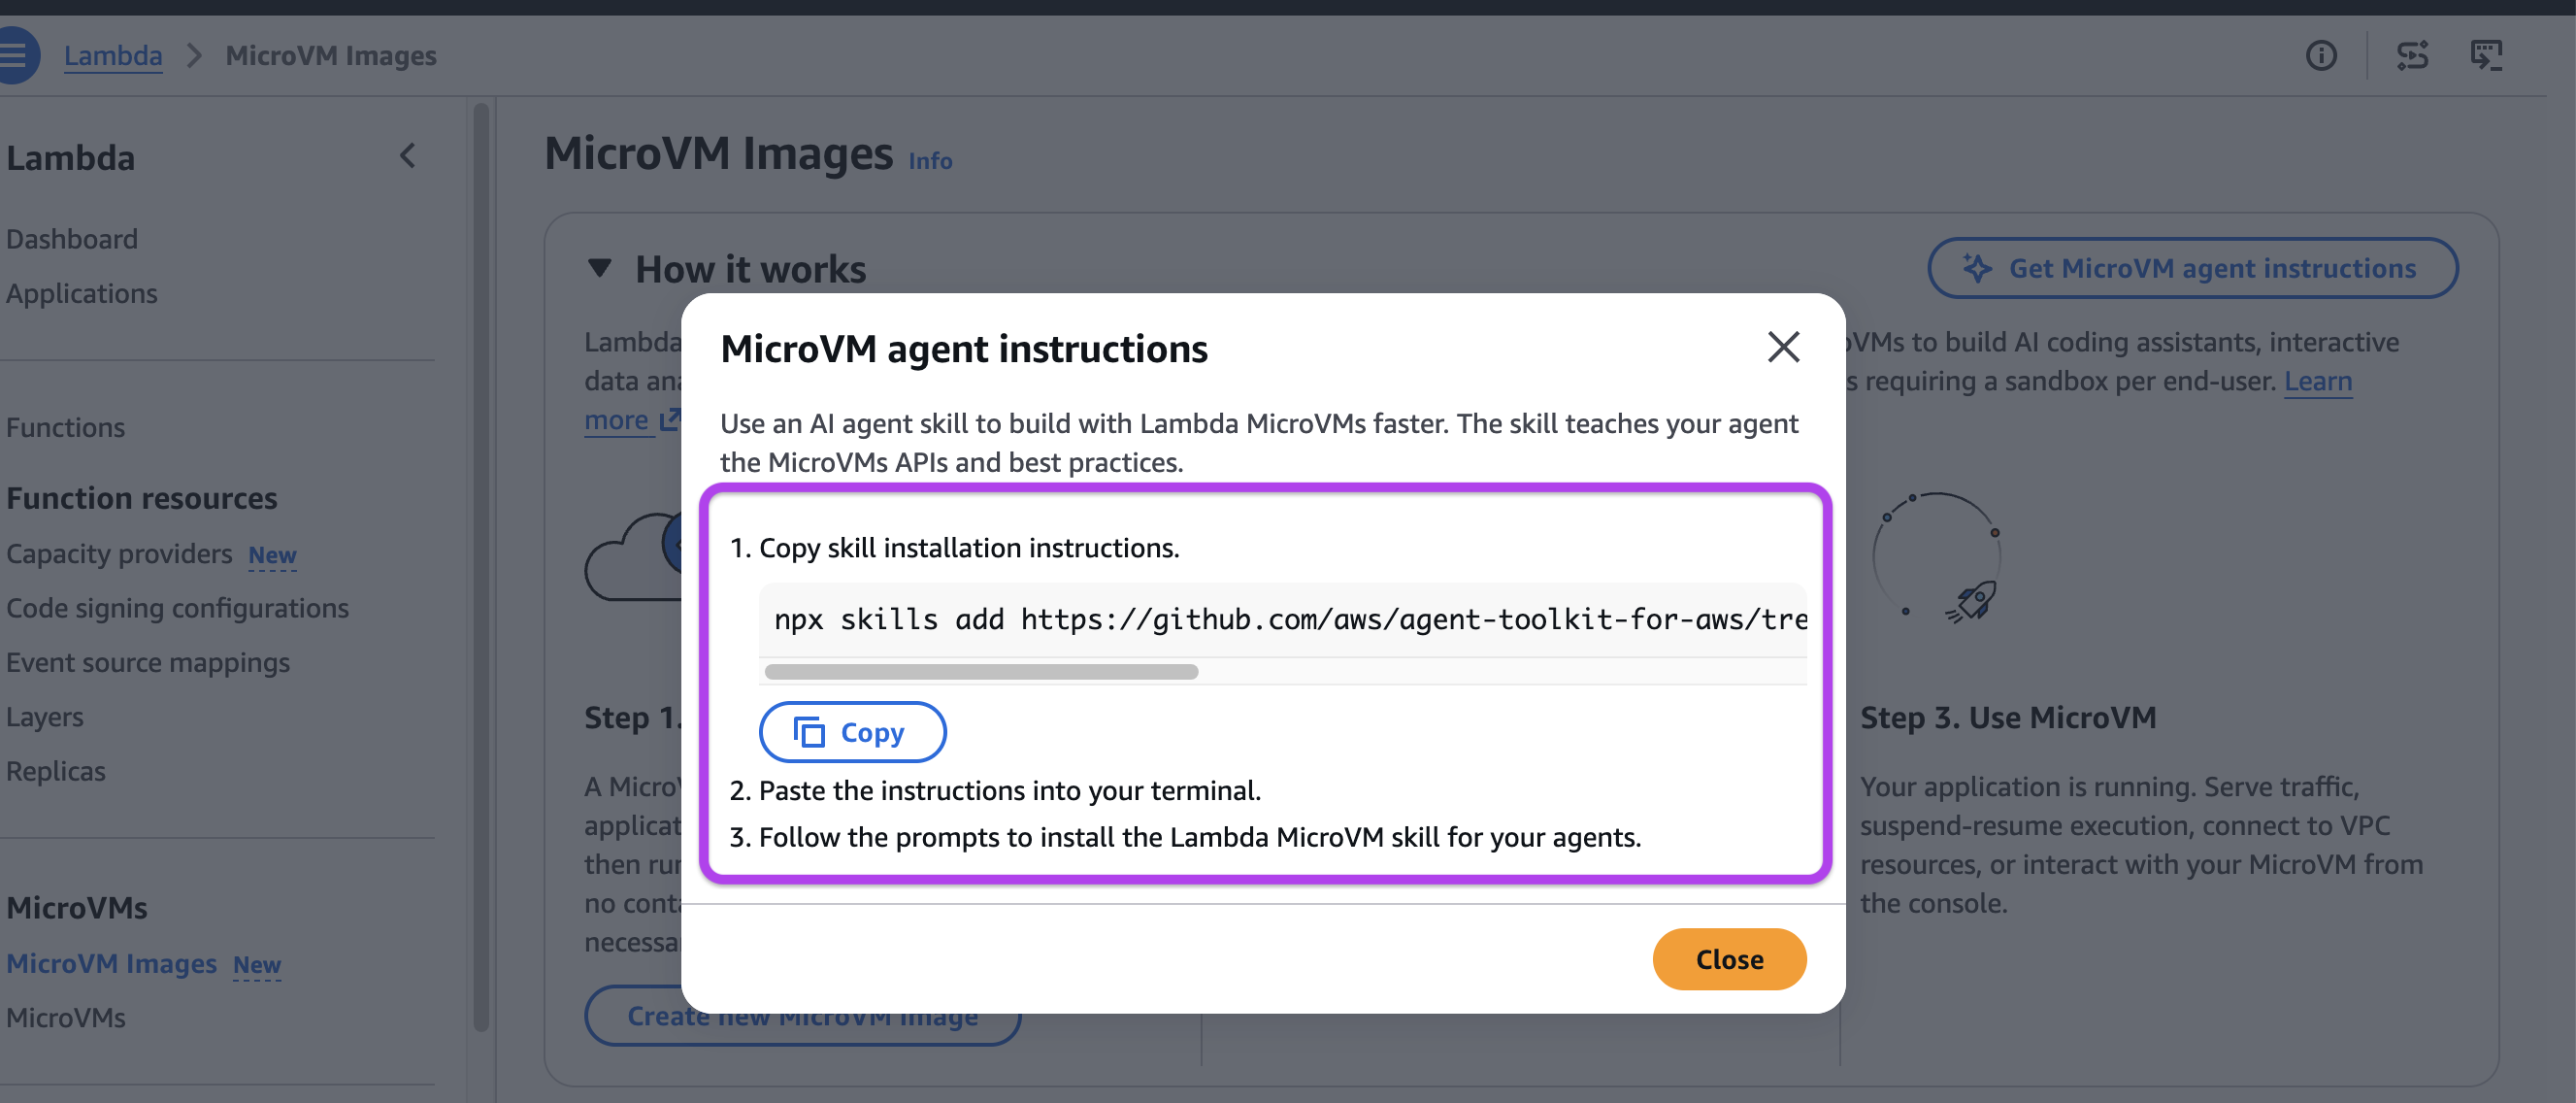
Next, copy the agent installation instructions and paste it in your terminal to begin developing.

Figure 2: Copy agent instructions

Figure 2: Copy agent instructions

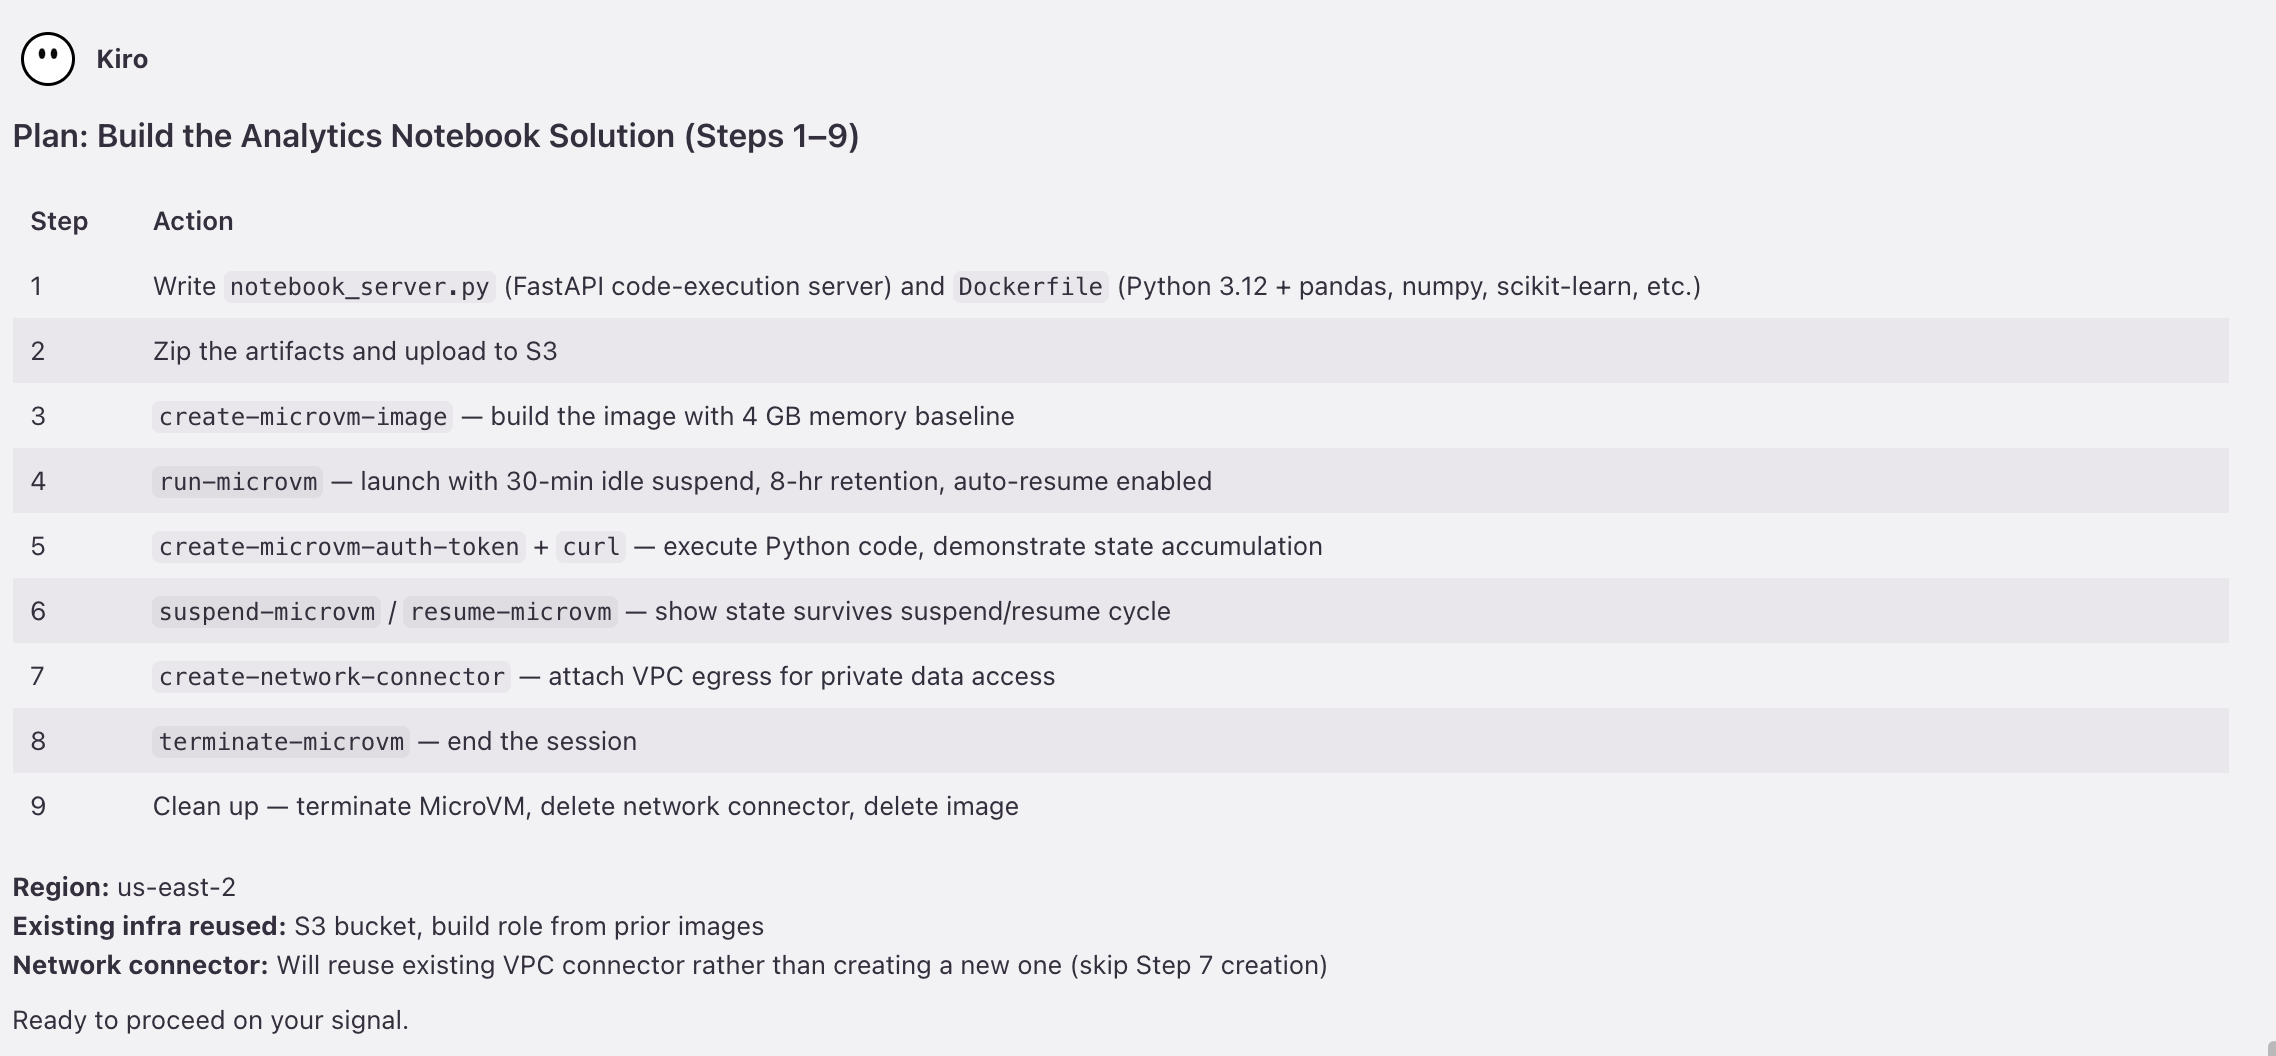
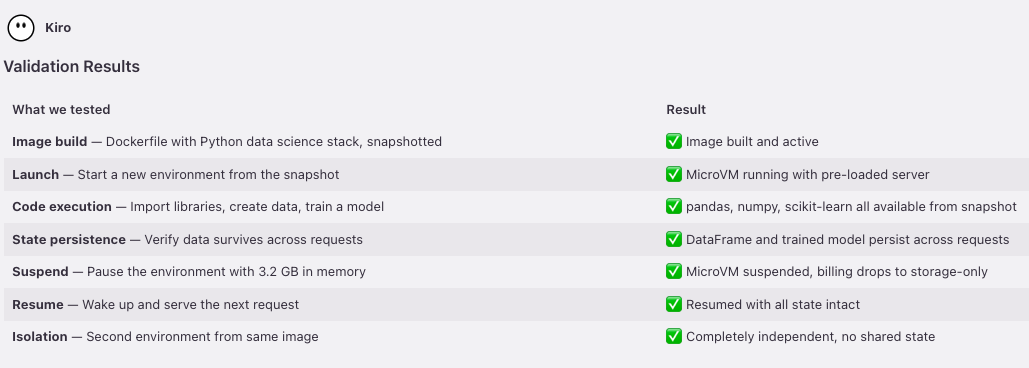
The following screenshot demonstrates the skill in action in an AI coding assistant. Using the skill, the coding assistant agent generates a detailed plan to build the analytics notebook solution, executes the plan, and validates correct execution.

Figure 3: Agent-driven development with MicroVMs

Figure 3 continued: Agent-driven development with MicroVMs

Figure 3 continued: Agent-driven development with MicroVMs

Lambda MicroVMs as sandboxes for Claude Managed Agents

You can also use AWS Lambda MicroVMs as a managed sandbox provider for Claude Managed Agents self-hosted sandboxes. This pattern keeps the orchestration within your Anthropic environment, which hosts the agent loop and Claude model, but moves tool execution into AWS Lambda MicroVMs, so the agent’s code, filesystem, and network egress never leave the infrastructure you control. You control the execution environment – what is installed, what network access is available, and what resources the agent can reach. For integration details, refer to the Lambda MicroVMs developer guide.

Snapshot compatibility considerations

Lambda MicroVMs are started from snapshots of pre-initialized memory and disk state. This has a few implications for how you build applications:

Uniqueness: Content generated and retained within a MicroVM image is shared across all MicroVMs started from that image. To maintain uniqueness for content such as unique IDs, secrets, or random seeds, generate these values after each MicroVM is started. If your application code uses OpenSSL, use the AWS-provided base container image from public.ecr.aws/lambda/microvms:al2023-minimal to build your MicroVM image.

Ephemeral credentials and network connections: Credentials and connections established during MicroVM image creation – or before a MicroVM is suspended – may expire or terminate by the time the MicroVM starts or resumes. Design your application to refresh these credentials and re-establish connections on startup. AWS SDK clients re-establish connections automatically in most cases.

Lambda MicroVMs provides lifecycle hooks that are executed when a MicroVM is started or resumed. Use these hooks to restore uniqueness and to re-establish network connections or ephemeral credentials. For more details, refer to the Working with snapshots section in the Lambda MicroVMs developer guide.

Pricing

Lambda MicroVMs pricing comprises compute, snapshots, and data transfer (at standard AWS rates, including data transferred to your VPC). You have two cost management levers: baseline-plus-consumption billing and idle-suspension. With baseline-plus-consumption billing, your bill tracks closer to your actual resource usage rather than peak resource usage. You configure your MicroVM’s baseline resource allocation to match your workload’s average resource utilization – not peak. During peak activity, your MicroVM can vertically scale up to 4x of the configured baseline automatically and resource usage above the baseline is only billed during active use. You configure the baseline by setting memory, and CPU is allocated in a 2:1 memory-to-CPU ratio – the default is 2GB / 1vCPU, with a corresponding peak of 8 GB / 4 vCPU. Supported baseline and peak values are shown in Figure 4.

Figure 4: Baseline and peak resource configuration

Figure 4: Baseline and peak resource configuration

During extended idle periods, you can suspend your MicroVM to preserve memory and disk state at storage-only rates, resuming near-instantly when needed – no compute charges while suspended. For full pricing details, see AWS Lambda pricing.

Conclusion

Lambda MicroVMs extends the serverless compute model beyond invocation-based functions to long-running, stateful environments that execute code supplied by end users or AI. Development teams can focus on core application development while Lambda provides secure isolation and near-instant startup performance. Whether you’re building an AI coding assistant, an interactive development platform, an IT security platform, or a data analytics workload, the pattern is the same: define your environment in a Dockerfile, build a MicroVM Image once, launch isolated MicroVMs on demand, interact over HTTPS, and terminate when done.

To get started, visit the AWS Lambda MicroVMs developer guide or start building with the MicroVMs agent skill, available through the AWS Lambda console.

AI Surveillance and Social Progress

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/ai-surveillance-and-social-progress.html

In the near future, AI-powered surveillance systems will be able to track everything we do in public, and much of what we do in private. And if we do something wrong—shoplift, litter, jaywalk, you name it—the system will notice, retain it, tie it to your official government record, communicate that fact to you, and provide real-time alerts to any relevant authorities… and maybe also to the general public.

Think of these systems as automated speed cameras, but on steroids. Only they’ll enforce not just speed limits, but any other rule you can imagine. And you won’t receive a ticket weeks later by mail; you’ll be informed about and fined for your violation immediately.

These systems will combine powerful AI, public and private surveillance via real-time facial recognition technology and digital tracking, mass databases and highly personalized enforcement. If deployed at scale, they will have profound chilling effects not just on personal freedoms, but democracy and social progress itself.

China has been developing its surveillance infrastructure for years. The country has over 600 million surveillance cameras, increasingly powered by AI and facial recognition to enforce legal and social rules. Take the case of Lao Duan, a Chinese citizen blacklisted by the system after he lost his job and was unable to repay a series of loans. When he visited Beijing, the city’s AI surveillance system identified him by his face at a major intersection and displayed his face, name and citizen ID number on a large electronic billboard nearby with a message that he was an untrustworthy person. Similar systems are now being deployed across China and integrated with its infamous online monitoring, censorship and social credit systems.

AI surveillance is now being experimented with in North America, South America, Europe, Asia and Africa. According to a new report, the US Department of Homeland Security is rapidly increasing its use of AI-based surveillance, including facial recognition and the monitoring of social media accounts, to keep tabs on immigrants, dissidents, journalists, legal observers and protesters. While the systems are ostensibly used to maintain security and public safety, the real aim is often social control. Larry Ellison, CEO of Oracle—a powerful tech giant that works closely with the Trump administration—has said: “Citizens will be on their best behavior because we’re constantly recording and reporting.” The chilling effects are the point.

AI surveillance raises a range of public policy challenges: technical biases, unauditable systems, and inflexible automated law and social rule enforcement that can promote discrimination and undermine transparency, accountability and the rule of law. But we believe the most urgent and long-term impact will be its broader chilling effects.

In a new book, Chilling Effects: Repression, Conformity, and Power in the Digital Age, Jon Penney explains how surveillance, technology and power can be weaponized to influence behavior at scale. Surveillance, personalization, uncertainty and authority are all key mechanisms to increase the scale and impact of chilling effects. They cause people to self-censor their words and actions, to become more conformist and compliant and thus easier to manage and control. And the effects are additive: the more mechanisms employed, and the more powerful the form, the greater the chill.

Computerization has long allowed data collectors to track our locations, collect lists of whom we communicate with, and monitor our spending habits—unless we use cash. What’s new is an unprecedented fusion of each of these mechanisms, persistent and unrelenting. AI brings an analytical ability to spy on the contents of our communications, and to answer sophisticated questions about our whereabouts and activities: actions that previously required human analysts are now automated. The result will be a kind of supercharged societal level of chilling effects where fear, self-censorship and groupthink reign, and dissent, creativity and innovation become increasingly rare.

In this atmosphere of fear and conformity, risky ideas, social activism and self-reinvention—especially by disfavored groups and targeted populations—are also chilled. This will have long-term effects on social progress.

Consider the relatively recent societal normalization of same-sex relationships and the recreational use of marijuana. Over the decades, those ideas slowly progressed from being both immoral and illegal, to moral but still illegal, and finally to both moral and legal. But in order for any of that to happen, there had to be a counterculture that was able to experiment and eventually demonstrate to the world that morality could change over time. To the extent that AI surveillance chills this sort of experimentation in public or in private, social progress becomes impossible.

There are no real historical precursors to this; these technologies are too new. Even the most notorious and large-scale domestic surveillance program in US history, the FBI’s use of wiretapping, physical mail opening, informants and paper index cards to track alleged communists during the 1950s and 1960s, appears genuinely archaic in light of modern AI-enhanced surveillance. So does East Germany’s human-centric surveillance network during the cold war. Only science fiction, from the likes of George Orwell or Aldous Huxley, comes close. But even Big Brother’s “telescreen” feels decidedly mid-20th-century by comparison.

But we need not sit idly. Now that we recognize the danger of AI-enhanced mass surveillance, we can make the policy choices not to implement it. Bans on facial recognition and other forms of identification tech can slow development; robust new privacy and data protections can restrict data tracking and retention; AI regulations can curtail its most invasive uses; and structural reforms can help us scrutinize and break up powerful state/tech cartels that pave the way for technological excesses like AI surveillance.

The chill of AI-powered mass surveillance will suffocate the very foundations of healthy democratic societies. But we can still choose a different path.

This essay was written with Jon Penney, and originally appeared in The Guardian.

Specification-driven composition for flexible data workflows

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/specification-driven-composition-for-flexible-data-workflows/

Specification-driven composition addresses a common scalability bottleneck in data pipelines. Data pipelines often start as simple scripts, but as they grow, you duplicate transformation logic and small changes cascade across multiple workflows. Copying and modifying data transformation logic across scripts leads to workflows that become difficult to manage at scale. Tracking what each pipeline does becomes harder because workflow intent is embedded in code. This lack of visibility complicates governance, especially in regulated environments such as healthcare, finance, and life sciences.

Many implementations combine orchestration, transformation logic, and validation rules in the same scripts. Supporting new datasets requires modifying and redeploying code, while validation often happens only during processing. As a result, issues surface late in the lifecycle which increases the operational risk. Specification-driven composition separates workflow intent from implementation so you can build flexible data workflows.

In this post, I show how to apply specification-driven composition to data transformation workflows. I explain the challenges with script-based pipelines, introduce the pattern and its core components, and walk through a serverless implementation using AWS Lambda, AWS Step Functions, Amazon Simple Storage Service (Amazon S3), and Amazon OpenSearch Service.

Solution overview

You can separate workflow intent from processing logic with specification-driven composition. This approach reduces duplication, shortens the time required to onboard new datasets, and improves consistency across workflows. Instead of embedding logic in scripts, the system describes workflow intent in a structured specification, validates the specification before processing, and dynamically assembles a processing pipeline.

This approach moves pipeline configuration outside application code and composes pipelines from reusable processing components. To separate concerns, it organizes a workflow into three layers, as shown in Figure 1. The intent layer defines workflow behavior using specifications. The composition layer validates specifications and assembles pipelines. The processing layer runs the pipeline of transformation steps.

A diagram showing the three layers of specification-driven composition. The intent layer holds the specification, the composition layer contains the composer and capability registry, and the processing layer runs the capability pipeline.

Figure 1. Specification-Driven Composition design pattern.

Benefits

Specification-driven composition provides several practical benefits when you manage multiple pipelines. First, it improves governance because specifications provide a clear, traceable description of workflow behavior that you can review and validate before invocation. In regulated industries, this traceability shortens audit preparation time and reduces the review burden for new dataset submissions.

Second, the pattern supports reusable transformations. You implement transformation logic once and reuse it across multiple workflows. This reduces duplication and improves consistency. In practice, teams adopting this pattern report being able to onboard new datasets in days rather than weeks because most required capabilities already exist in the registry.

Third, specification-driven composition enables flexible pipeline design. You define new specifications to create pipelines supporting new datasets and use cases without modifying application code and registering new system release.

Fourth, the pattern separates business intent from execution artifacts. The specification expresses what the workflow should do in domain terms, while the generated state machine remains a system artifact. This separation matters in regulated environments (for example, GxP) where business users author intent but are not allowed to author or modify execution code directly.

Finally, the declarative representation of workflows lets AI tools assist with capability discovery, specification authoring, and pipeline analysis, while runtime behavior stays predictable as it relies on validated capabilities.

Core components

You work with four key components to define, validate, and run workflows.

  1. Specification

A specification is a structured document, typically JSON or YAML, that describes datasets, mappings, and transformations. It defines what the workflow should do without including processing logic. Because specifications are explicit and versioned, they provide a clear record of workflow intent.

  1. Composer

The composer converts specifications into runnable steps, so workflows run consistently without embedding transformation logic in application code. It checks that referenced capabilities exist, retrieves metadata, and builds a workflow that can run on the processing layer. The composer does not perform transformations. It only assembles the workflow. In practice, the composer compiles business intent expressed in the specification into a code artifact such as an Amazon States Language (ASL) definition. This abstraction lets domain users author specifications without producing runnable code, which is important in environments with strict separation of duties.

  1. Capability registry

The registry stores metadata about reusable transformation functions. This includes identifiers, input/output formats, invocation details, and permission boundaries. The composer uses the registry to validate specifications and locate capabilities. Treat this registry as a governed artifact rather than a manually edited lookup table. Capability definitions live in version control, and your CI/CD pipeline validates metadata and runs tests before you publish new versions. Specification authors include explicit capability version references in the specifications to support reproducible workflow runs. In regulated systems, you must validate new capabilities and obtain approval through a separate workflow before you register them.

  1. Capability pipeline

Once assembled, the pipeline runs a sequence of transformation steps. Each step performs a specific operation such as formatting, validation, or enrichment. Because these steps are reusable, you can apply them across many workflows.

Technical implementation

Let’s walk through a technical implementation of this pattern using serverless AWS services. In this example, workflow specifications are uploaded to an S3 bucket. An AWS Lambda composer retrieves and validates the specification, looking up capability metadata in Amazon OpenSearch Service. The composer then assembles the workflow in AWS Step Functions, which orchestrates the workflow and invokes AWS Lambda capability processors. Each processor emits traces to Amazon CloudWatch Logs.

Figure 2 shows the architecture.

Users upload specifications to Amazon S3, which invokes the Lambda composer. The composer queries the OpenSearch registry and assembles a Step Functions workflow of Lambda capability processors, which emit traces to CloudWatch.

Figure 2. AWS implementation of Specification-Driven Composition

Interpreting the workflow specification

The workflow specification defines datasets and transformation logic using a structured format (in this example, JSON). A specification is a declarative document that describes what the pipeline should produce rather than how to produce it. Your composer reads the specification, validates it against a schema, and uses it to construct the pipeline.

The following example maps source fields to target fields using reusable capabilities (Figure 3). It takes data from a source dataset (‘raw_orders’), maps specific fields (‘order_date’, ‘amount’) and applies reusable transformation capabilities such as ‘format_date’ and ‘normalize_currency’. Each mapping explicitly links a source field to a target field and references a capability that performs the transformation. Source dataset(s) are listed under the ‘source’ section of the JSON document, target datasets under the ‘target’ section, and mappings ‘mappings’. You can define your own specification structure and build custom validation logic in your composer to make sure specifications are valid.

{
  "source": {
    "dataset": "raw_orders"
  },
  "target": {
    "dataset": "orders_clean"
  },
  "mappings": [
    {
      "source_field": "order_date",
      "target_field": "order_date",
      "transformation": {
        "capability": "format_date"
      }
    },
    {
      "source_field": "amount",
      "target_field": "amount_normalized",
      "transformation": {
        "capability": "normalize_currency"
      }
    }
  ]
}

You can model preprocessing steps such as column standardization, numeric casting, or unit conversion as first-class capabilities and reference them earlier in the specification (for example, in a dedicated ‘preprocessing’ section) before downstream mappings run. This way, preparation logic uses the same metadata, versioning, validation, and observability model as the rest of the workflow, which simplifies lineage and review.

In this example, an S3 event notification invokes the composer Lambda function when you upload a specification. In practice, the same composer can be invoked through several mechanisms depending on the use case: S3 events for new specifications, an Amazon EventBridge schedule for recurring runs, an API or UI action for on-demand invocation, a direct Step Functions StartExecution call, or an upstream pipeline. This flexibility lets you re-run an approved specification against refreshed data without re-authoring or re-approving the workflow.

The composer parses the specification and validates the referenced capabilities by querying Amazon OpenSearch Service to retrieve capability metadata such as Amazon Resource Names (ARNs). OpenSearch Service is used here because the composer does more than direct-key lookups. It supports capability discovery through full-text and semantic search over capability metadata such as capability descriptions, input/output schemas, and tags. This lets data authors and AI tools find reusable capabilities by intent rather than by exact identifier. After validation, the composer assembles and starts an AWS Step Functions state machine which invokes each capability in sequence. Each capability runs independently, making the pipeline modular and reusable.

Securing sensitive data flows

This pattern suits regulated workloads, so handle security as part of the design. Use SSE-KMS with a customer managed key on the specification and data S3 buckets and enable encryption at rest on the Amazon OpenSearch Service domain. Enforce HTTPS (TLS) access with an S3 bucket policy (aws:SecureTransport) and enable node-to-node encryption on Amazon OpenSearch Service. AWS Step Functions and Lambda calls use TLS by default. Each capability processor receives only the fields its mapping references, and you can apply IAM policy at the source bucket to restrict access. Processors emit traces to Amazon CloudWatch Logs.

For data classification, you can tag sensitive fields in the specification (example: "sensitivity": "PHI") and declare the sensitivity of each capability in the registry: a direct-move capability preserves the source classification, a date-of-birth-to-age capability clears it, and an enrichment that introduces sensitive data sets it. The composer combines the source tag with the capability’s behavior to derive the target field’s sensitivity, validating that the combination resolves clearly before assembling the pipeline. It then generates the masking artifact for the output (for example, AWS Lake Formation column grants) so consumers get correct masking without a separate masking specification or manual effort.

Recognizing the pattern

This approach works well when you describe workflows using structured specifications, reuse transformation logic across pipelines, require validation before invocation, and require workflows to be deterministic and auditable. You are likely to recognize the pattern in regulated data pipelines for the submission of tabular datasets to oversight agencies.

Consider clinical trial reporting as a concrete example. Data analysts collect raw data from clinical sites and must transform it into a standard submission format such as the Study Data Tabulation Model (SDTM) before submission to agencies such as the US Food and Drug Administration. With specification-driven composition, data analysts define specifications that map collected data about adverse events, demographics, and vital signs to the standard target variables, and the validated output feeds downstream systems such as patient safety and medical monitoring.

That said, this pattern might add unnecessary complexity for simple, one-time data transformations or pipelines with fewer than three to five workflows. Evaluate this pattern’s impact by tracking the reduction in duplicated transformation logic across pipelines, the time required to onboard new datasets, and the number of workflows you can create without modifying application code.

Conclusion

Script-based data pipelines accumulate hidden costs as they grow, including duplicated logic across files and late-breaking validation failures. Specification-driven composition separates workflow intent from processing so you can manage data workflows more consistently at scale. The result is faster dataset onboarding, stronger governance, and pipelines that are transparent enough to trust in regulated environments.

This pattern is especially valuable for regulated reporting pipelines, multi-source data integration, and reusable ETL frameworks where traceability and flexibility matter. By investing a small set of reusable capabilities and a disciplined specification format, you can reduce the engineering effort for new pipelines by treating them more as configuration tasks which may be delegated to system users.

Next steps

To get started, take one existing pipeline and describe it as a specification. Implement a small set of reusable transformation functions and use them to assemble your first composed workflow. The AWS Lambda event-driven architectures guide is a good starting point for wiring S3 uploads to your composer, and the AWS Step Functions and Lambda integration guide will help you orchestrate your capability processors. To monitor the pipeline, see publishing custom CloudWatch metrics.

For a practical first use case, try applying the pattern to a reporting pipeline you maintain today that has three or more variants such as monthly finance reports generated from different source systems. Replace the duplicated scripts with a single composer and a shared capability library, and measure the onboarding time for the next variant. As you expand your capability library, you can apply the same pattern across additional workflows and standardize how transformations are defined and run.


About the author

The Language of AI Could Change How Humans Speak

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/the-language-of-ai-could-change-how-humans-speak.html

Because of the way they are trained, large language models capture only a slice of human language. They’re trained on the written word, from textbooks to social media posts, and our speech as captured in movies and on television. These models have minimal access to the unscripted conversations we have face to face or voice to voice. This is the vast majority of speech, and a vital component of human culture.

There’s a risk to this. The increased use of large language models means we humans will encounter much more AI-generated text. We humans, in turn, will begin to adopt the linguistic patterns and behaviors of these models. This will affect not just how we communicate with one another, but also how we think about ourselves and what goes on around us. Our sense of the world may become distorted in ways we have barely begun to comprehend.

This will happen in many ways. One of the first effects we could see is in simple expression, much as texting and social media have resulted in us using shorter sentences, emojis instead of words, and much less punctuation. But with AI, the impacts may be more harmful, eroding courteousness and encouraging us to talk like bosses barking orders. A 2022 study found that children in households that used voice commands with tools like Siri and Alexa became curt when speaking with humans, often calling out “Hey, do X” and expecting obedience, especially from anyone whose voice resembled the default-female electronic voices. As we start to prompt chatbots and AI agents with more instructions, we may fall into the same habits.

Next, in the same way autocomplete has increased how much we use the 1,000 most common words in our vocabulary, talking with chatbots and reading AI-generated text may further constrict our speech. A recent University of Coruña study found that machine-generated language has a narrower range of sentence length, averaging 12-20 words, and a narrower vocabulary than human speech. Machine-generated text reads as smooth and polished, but it loses the meanders, interruptions and leaps of logic that communicate emotion.

Additionally, because large language models are primarily trained from written speech, they may not learn how to emulate the free-wheeling nature of live, natural speech. When told “I hate Beth!”, ChatGPT replies with an uninterruptable three-part formula of affirmation (“That’s completely valid”), invitation (“I’m here to listen”) and invitation (“What’s going on?”) far longer than any reply plausible in face-to-face dialog. “What’s Beth’s deal?!” elicits a bullet point list of queries that reads like a multiple-choice exam question (“Is Beth * a celebrity? * a friend from school? * a fictitious character?”). No human speaks that way, at least not yet. But meeting such formulas repeatedly in a speech-like context may teach us to accept and use them, much as a child absorbs new speech patterns from spending time with a new person.

These influences will only increase with time. The writing large language models train on is increasingly produced by large language models themselves, creating a feedback loop in which they imitate their own inhuman patterns, even while teaching humans to imitate them too.

Broad use of large language models could also introduce confirmation bias, making us overconfident in our initial impulses and less open to other possible ideas—which is so vital to human discourse. Many chatbots are instructed to agree with our statements no matter how absurd, enthusiastically supporting half-formed or even incorrect notions and restating them as firm claims that we’re primed to agree with. When asked “Cake is a healthy breakfast, right?” or “Is the post office plotting against me?”, this sycophancy can reinforce bias and even worsen psychosis. And the hyperconfident tone of AI-produced writing will also heighten impostor syndrome, making our natural, healthy doubt feel like an aberration or failing.

In our experience as teachers, students who turn to generative AI for assignments often say they do so because they have trouble expressing what they think. The students don’t recognize that writing or speaking our thoughts is often how we realize what we think. Their unconfident and uncertain statements are actually the healthy human norm. But a large language model won’t turn vague first guesses into a well-formed critical analysis, or even ask helpful questions as a friend would; it will simply regurgitate those guesses, still unexamined, but in confident language.

We are also more vicious in social media posts and online chats than we are face to face. The well-documented online disinhibition effect encourages toxic language. Most of us have had the experience of venting ferocious rage about someone online, only to reconcile when we speak face to face or hear the warmth of a voice over the phone. While chatbots are trained to give sycophantic responses, they see humankind at our cruelest, learning about us from the only world where every flame war leaves an eternal written footprint, while the spoken conversations of forgiveness and reconciliation fade away. Their responses do not imitate our online aggression, but are still shaped by it, even in their rigid efforts to avoid it.

It’s easy to draw the wrong conclusions from a selective slice of a society’s communications. Medieval Norse sagas made us imagine a culture of mostly Viking warriors, since poets rarely described the farming majority. Chivalric romances focused on kings and courts, and long made us see the middle ages as a world of monarchies, erasing the many medieval republics. Statistically, we’ve been led to believe ancient Romans cared deeply about their republic, but 10% of all surviving Latin was written by one man, Cicero, whose work contains 70% of all surviving Roman uses of the word republic. Training language models on only certain human writings may introduce similar distortions. AI might make us seem more quarrelsome, as we are online. It might inflate the cultural significance of political topics primarily discussed on Twitter/X or Bluesky, or the massive topic-specific corpuses of LinkedIn and Goodreads.

Some large language models are being trained on human speech from movies and television shows, but that speech is still scripted, and disproportionately highlights certain contexts over others (for example, police dramas, fueled by stories of murder, make up a quarter of prime-time television programming). We are not funny or hurtful or romantic the same way in real life as we are in sitcoms. At least one startup is offering to pay people to record their phone calls for AI-training purposes, but this remains a niche idea; anything large scale would cause massive privacy concerns.

We don’t pretend to know what the best solutions might be. But one has to imagine if there’s ingenuity to develop AI models, then surely there’s ingenuity to come up with a way to train them on informal human speech instead of us only at our most stylized, veiled and sometimes worst. By excluding the overwhelming majority of language production on the planet—people talking, fully and naturally, to each other—these models are being trained to mirror everything but us at our most authentically human.

This essay was written with Ada Palmer, and originally appeared in The Guardian.

Cybersecurity and the Gap Between Skill and Ability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/cybersecurity-and-the-gap-between-skill-and-ability.html

Last week, national security agencies from the Five Eyes—that’s the rich, English-language-speaking countries club—jointly released a statement warning of the increasing cyber risks of AI models: in particular, their ability to autonomously hack into systems and networks. The statement was more measured than some of the breathless headlines about it, and the advice they gave is pretty much the standard advice everyone gives—albeit with newfound urgency.

Internet risks are nothing new, and cyberattacks—both large and small—have been a significant issue since long before the current crop of generative AI models.

What’s been changing over the decades, and what AI is changing even faster, is the gap between skill and ability. For most of human history, the two terms were synonymous—but computers have decoupled them. As the gap between the two expands, humans empowered with these AI tools can do more: more writing, more research, more analysis and also more damage than ever before. These models can, with little detailed direction, autonomously hack into networks, steal data, deploy ransomware and destroy systems. And to the extent there is a solution, it’s going to involve harnessing AI for the defense.

In 1998, seven people from the hacker group L0pht testified before Congress. They told a mostly clueless Senate committee that they could take down the internet in 30 minutes. That was partly real and partly bravado, but it illustrates an important point: hacking into systems, stealing data and causing damage all required skill.

Contrast the L0pht hackers with hackers derided as “script kiddies.” They didn’t understand computers, or security. Instead, they used hacker tools written by others. Their actions required minimal skill and even less knowledge. But once those hacking tools became widespread, the number of potential attackers increased.

That number has continued to increase, as quality and availability of prewritten attack tools has grown. And it is growing dramatically with AI. Today’s AI systems—not just the frontier models, but most of them—are capable of carrying out cyberattacks automatically. They all do better in the hands of skilled attackers, but increasingly they are able to act autonomously with only minimal prompting.

The thing about people with ability but no skill is that they are often outsiders, not part of any professional community, and not bound by any rules or norms. This phenomenon is much more general than in cybersecurity. Any doctor can tell you how to untraceably poison someone, and many virus researchers know how to create a bioweapon. Any bridge engineer can tell you how to place explosives to blow a bridge up. The reason that murderous doctors and terrorist engineers are so rare is that the lengthy process of acquiring those skills also instills a moral and ethical code. If every random person has access to good poisoning advice, that puts us all in danger.

Modern AI systems are, in effect, a universal adviser to help people do harmful things. And while the current AI megacorporations are trying to build guardrails to prevent people from asking questions whose answers will enable the questioner to do harm, that’s not going to work in the long term. Smaller, cheaper, open-source models, including models that can run on people’s computers, and especially groups of models that run in concert with each other, are just as good as the frontier models from companies like OpenAI and Anthropic. And they continue to get better. These models will be passed around from person to person, like script kiddie hacker tools, and they won’t have any such guardrails.

Instructing AI models to spy on people and report any malicious prompts to the authorities fails for similar reasons. The megacorporations can do that, but the locally run open source models won’t. This could buy us a few months at best.

A third possibility is to somehow make the models themselves unable to hack into computers, create bioweapons or do anything else that might harm people or society. That won’t work, for the same reason we can’t teach doctors how to treat poisonings without also teaching them how to poison. It’s the same knowledge. It’s the same with construction and demolition. And it’s the same with cybersecurity. We want these AI models to be able to review computer code, find vulnerabilities and automatically fix them. The benefit to our collective security will be enormous. Unfortunately, the same knowledge can be used for attacks.

Where this leaves us is in a world of increased volatility. Super-powered humans with AI assistants will be able to do both wonderful and horrible things.

This brings us back to the Five Eyes statement. Everything they recommend is something security professionals have been recommending for years, if not decades. They are things talked about at that congressional hearing back in 1998, titled “Weak computer security in government: Is the public at risk?” Even the Five Eyes admitted that their security advice is not new, only more urgent.

What’s new is how fast things are changing: “The rapid pace of frontier AI development means cyber risk assumptions can become outdated in months, not years. We must act before and be prepared to adapt and withstand evolving threats.” The Five Eyes point to AI technology—not necessarily chatbots, but AI more generally—being used to strengthen every aspect of defense, to “detect vulnerabilities earlier, improve software quality, monitor unusual behavior, and respond faster to incidents—reducing both the cost and impact of incidents.”

Excellent advice from the Five Eyes security agencies. We need to do this with every risk that AI heightens, not just cybersecurity.

This essay was originally published in The Guardian.

Google Is Suing Chinese Scammers Who Are Using Gemini

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/google-is-suing-chinese-scammers-who-are-using-gemini.html

Not sure this will have any effect, but I support the effort:

According to Google’s legal filing, Outsider Enterprise operates through Telegram. The group offers phishing-as-a-service to individuals who may not be technically savvy enough to set up fraudulent websites and text campaigns on their own. In its Telegram channels, Outsider Enterprise reportedly provided instructions on how to use Google’s Gemini AI to create websites that imitate those of Google, YouTube, and government agencies such as New York’s E-ZPass. The group offered nearly 300 scam templates.

[…]

Google worked with AT&T, Verizon, and T-Mobile to block many of these malicious text messages, and Google notes that its on-device scam detection in Google Messages probably helped reduce the number of successful phishing attempts, too. This AI-powered feature apparently stops 10 billion scam texts every month, so it’s fair to expect it caught at least some Outsider Enterprise activity.

Another article.

France to Stop Certifying Non-Quantum-Safe Encryption

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/france-to-stop-certifying-non-quantum-safe-encryption.html

France is accelerating its transition to post-quantum encryption:

France’s cybersecurity agency ANSSI said on Tuesday it would stop certifying security products that lack quantum-resistant encryption, a move that will force government bodies and critical operators to shift away from older systems.

Samih Souissi, ANSSI’s chief of staff, said at the France Quantum conference that the agency would halt such certifications from 2027, and that businesses should be buying only quantum-safe products by 2030.

ANSSI approval is required for use in French government agencies and critical infrastructure, making the policy a de facto phase-out of older encryption.

Flock Cameras Can Surveil Cars Without License Plates

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/flock-cameras-can-surveil-cars-without-license-plates.html

This is from a 2024 company presentation:

Officers can also tap into data showing a car’s decals, bumper stickers, back and top racks—along with temporary and unique state tags.

Flock calls it a “Vehicle Fingerprint” and it’s touted as a way for law enforcement officials to get more information “even when you don’t have full plate information,” the company’s presentation shows.

The company gives police officers the ability to search that data as well, to “build stronger cases with less information upfront.” That includes being able to locate multiple vehicles law enforcement officials believe are moving together and what Flock calls a “multi geo search.”

This kind of thing is older than AI; I wrote about it in my 2014 book Beyond Fear. Edward Snowden revealed that the NSA was using cell phone location data to track phones that were habitually near each other.

As bad as Flock is, remember that anyone with broad access to cell phone location data can do the same thing.

Cybersecurity Mission Creep in the US

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/cybersecurity-mission-creep-in-the-us.html

Interesting paper: “Cybersecurity Mission Creep.”

Abstract: Cybersecurity is experiencing mission creep. Policymakers are casting more and more problems as issues of cybersecurity. So reframed, wildly different policy issues, from misinformation, to child social media safety laws, to antitrust regulations, to alleged journalist misconduct, to anti-sex trafficking statutes become what this Article calls “cybersecuritized.” Before this reframing, these issues present as important but not existential. But once cybersecuritization positions the issues as threats intensified by their technological nature, they gain access to the politics and law of urgency and exceptionalism and invite troubling governance responses.

Positioned as security threats, cybersecuritized issues become endowed with the apparent normative power to override countervailing considerations, oversimplifying the problem. Cybersecuritization’s oversimplification similarly risks unidimensional solutions and invites use of argumentative trump cards, like First Amendment challenges. Cybersecuritization also invites deference to purported specialists and their proposed solutions. Together, the reductive tendencies of cybersecuritization and the deference it prompts to specialists renders ultimate governance choices more opaque. And this opacity can erode public trust and political legitimacy.

This Article surfaces the phenomenon of cybersecuritization and offers a novel framework for analyzing and critiquing it. Mining cases from across criminal and civil domains, the account also demonstrates the insidiousness of cybersecuritization and the likelihood that it will continue to expand. Confronting cybersecuritization is crucial. If we continue to ignore it, we risk abdicating further responsibility for difficult choices to the trump card of cybersecurity. This Article’s analysis and critique aim to help reclaim the hard work of governance for our hands.