Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=WwgleEs2Uqs
How American Political Campaigns Are Using AI—and What They’re Spending on the Tools
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/10/how-american-political-campaigns-are-using-ai-and-what-theyre-spending-on-the-tools.html
This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.
New campaign finance disclosure data shines a light on which US political campaigns are using AI tools and how much they are spending on them.
Candidates’, parties’ and committees’ spending reveals that AI is fast becoming an essential tool of politics. The candidates themselves are quiet about how they are using the technology in their own campaigns. It’s a sensitive issue that we have been tracking closely since we started writing our book, Rewiring Democracy, which examined how AI is beginning to influence politics. A September 2025 Pew survey of Americans found that more than 70% would think less of a candidate if they used AI to help write a speech.
Itemized expenditure disclosure data from the US Federal Election Commission, dating back to 2020, reveals at least $17m in disclosed spending on AI technology vendors across 523 federal candidates and campaigns. Data from four states, California, Colorado, Massachusetts and Washington, provides a more localized picture going back to 2022.
Beginning with the AI behemoths, at least 80 federal campaigns and committees have reported spending with OpenAI since 2024. The total spending is not huge: only about $50,000 reported, skewing slightly more Republican than Democratic. The Republican National Committee is the largest overall buyer, with nearly $10,000 in reported expenses. Top individual users include the campaigns of Republicans Mike Lawler, John Kennedy and Bill Cassidy, as well as the California Democrats Ro Khanna and Ted Lieu. Most of these expenses are listed as office expenses, subscriptions to ChatGPT for staff, or research tools, rather than as specific political services. The company’s policies prohibit some political uses of their ChatGPT tool.
OpenAI’s biggest competitor, Anthropic, has rapidly built a similar level of usage, but with a different split. At least 65 candidates or committees now report paying the Claude maker in 2026, up from essentially zero in previous years, with a nearly two-to-one Democrat-to-Republican ratio. However, the largest individual user is the campaign of Tom Cotton, a Republican senator from Arkansas, who reported more than $4,000 in spend on Anthropic software in his June filing. Other major users are the Montana independent Senate candidate Seth Bodnar and Jason Knapp, who lost a Democratic House primary in Virginia, and the Democratic Alaska Senate candidate Mary Peltola.
Candidates use either Claude or ChatGPT, rarely both, according to the disclosures. Only about 12% of campaigns or committees using either tool reported expenditures to both vendors. The Democratic lean of Anthropic usage may reflect the company’s alleged liberal skew and clashes with the Trump administration.
In contrast, Elon Musk’s xAI caters to Republican interests and, accordingly, its meager usage comes almost entirely from the political right. Just seven federal and two state-level candidates or committees have reported paying xAI, a total of about $5,000, the majority of which was spent by the presidential campaign of RFK Jr in 2024, but also includes Republicans Dave McCormick and Thomas Massie.
More dollars go to the vendors specializing in political campaign applications of AI. For years, AmplifAI, which provides automated text messaging, essentially a new iteration on robocalling technology, was a dominant target of spending, soaking up $4.7m in campaign spending in the 2022 cycle alone. It was used heavily by Democratic candidates including Mark Kelly, Joe Biden, Bernie Sanders and Adam Schiff. Spending on AmplifAI, now owned by the troubled media conglomerate Triller, seems to have tapered off in the years since 2022.
The new rising Democratic solution for AI-powered text messaging is Daisychain, which has so far garnered about $300,000 in reported candidate spend in the 2026 cycle—up from only about $50,000 reported in 2024. More than half of this year’s spending comes from the Senate campaign of Democrat Abdul El-Sayed in Michigan.
The closest equivalent on the Republican side has been Campaign Nucleus, associated with former Trump campaign manager Brad Parscale. The AI-powered voter engagement tool has attracted six-figure spending from the Republican National Committee, multiple PACs aligned with Donald Trump, and five-figure investments from Mike Johnson, Kari Lake and other candidates. It is displacing the legacy Republican-serving texting vendor Prompt.io, which has retained about $375,000 in 2026 spending to date, down from more than $500,000 in the 2022 cycle. But it continues to be used: the A More Affordable California PAC sponsored by Uber has single-handedly spent more than $1m on Prompt.io in 2026. The Republican Massachusetts gubernatorial nominee Michael Minogue has been a recurring customer, as has the failed Republican California gubernatorial candidate Ché Ahn and Republican-aligned Super PAC Neighbors for a Better Colorado.
At the state level
At the state level, the AI spending is smaller but growing fast. Across the four states studied, we found a total of at least $92,000 in spending confidently attributable to modern generative AI vendors since 2022. The spending is spread across at least 108 candidates and committees. The growth has been explosive; there has already been about 10 times the amount of state-level AI spending reported in 2026 as there was in all of 2024.
Much of the state spending mirrors federal patterns. Daisychain again has the highest overall spend, and OpenAI and Claude dominate among the general-purpose AI vendors. DonorAtlas—the AI-powered prospect research tool—sticks out for its usage in these states, sitting behind only Daisychain and OpenAI and buoyed up by nearly $4,000 in spending by the California Democratic party.
Even though it has dominated so much media conversation, few candidates seem to be reporting spending on AI tools designed specifically to create synthetic audio and video, also known as “deepfakes”. We found just six federal candidates or committees reporting spending on the popular AI audio generator tool from ElevenLabs, with total spending of about $1,400 led by independent candidate for Colorado’s sixth congressional district Samir Witta. The AI image generator service Midjourney has five reported federal campaign or committee users reporting about $1,600, led by Sholdon Daniels, the Republican primary runner-up in the Texas 30th district. Combined, those two firms had less than $100 in reported spend across the four states.
However, recent data from the Wesleyan Media Project shows that at least 164 political ads in this cycle have included AI-generated media, supported by at least $80m in ad spending. What this illustrates is that candidate and committee disclosure reports are just the tip of the iceberg. They don’t cover spending on AI by political consultants, media firms and other vendors hired by the campaigns or by PACs, or independent committees raising and spending money aimed at boosting candidates’ campaigns. Those entities aren’t required to disclose detailed expenditure reports, and are very likely where the bulk of campaign AI usage is happening.
Since a large fraction of all spending in the campaign cycle will happen in the final weeks leading to November, much remains to be seen about the totality of how campaigns will leverage AI and what impact its use will have on voters’ decisions.
Политическата биография на един разстрел
Post Syndicated from Емилия Милчева original https://www.toest.bg/politicheskata-biografiya-na-edin-razstrel/
От гараж за производство на царевични пръчици до електрически ролсройс – биографията на 53-годишния бизнесмен Илиян Филипов е приказка за успеха. Но краят ѝ с изстрел от упор между очите е криминале.
Убийството на Филипов извади наяве двете му биографии. В едната той е едър предприемач, собственик на една от най-големите транспортни компании (PIMK) и други бизнеси с близо 3000 наети, както и на футболния клуб „Ботев“ – Пловдив. В другата биография e съдружник в строителна фирма със заподозрения като негов убиец С.М., чието криминално досие съдържа присъди за убийство и грабеж и обвързаности с Христофор Аманатидис – Таки.
Убийството показа и двете му жени – съпругата му и друга, от която е очаквал дете. Разкри и близостта му с министъра на вътрешните работи Иван Демерджиев, който потвърди, че го познава – „като познат“, но отрече да му е бил адвокат. И вицепремиерът и министър на финансите Гълъб Донев отрече Филипов да e сред физическите дарители при създаването на „Прогресивна България“. Разбира се, напълно възможно е всичко това да е било извършвано и без да оставя документални следи. А собственикът на PIMK все пак беше начело на пловдивските бизнесмени при срещата с Румен Радев преди изборите на 19 април.
В България публичният разказ за забогатяването обикновено премълчава отношенията с властта. В биографиите на успелите няма място за онези, които са вземали решения в тяхна полза. Въпреки че зад много от големите богатства стоят приватизационни сделки и обществени поръчки, а нито едно от двете не може да се реализира без политически протекции.
Политическите убийства не се ограничават до убийства на политици. Техни жертви могат да бъдат и бизнесмени, когато отстраняването им е свързано с борба за власт, политически интереси или опит да се повлияе на определени политически процеси. Парите и зависимостите им ги превръщат в участници в политиката.
Самата близост с управляващите обаче не доказва политически мотив за убийството. Тя задължава разследването да провери и тази връзка – особено когато след смъртта се разкрива влияние, премълчавано приживе.
Кой и защо поръча убийствата на Илия Павлов, Емил Кюлев, Петър Христов, Алексей Петров? Различни години, различни бизнеси, различни политически връзки и все същата липса на убедителен публичен отговор. Убийствата прекъсват живота им, но оставят недосегаеми отношенията, чрез които са натрупали пари и влияние.
Неразкрито убийство – скрити зависимости
Банкерът Кюлев е показно екзекутиран през 2005 г. – застрелян е в джипа си BMW X5 на столичния булевард „България“. Президентът Георги Първанов определя престъплението като „показно убийство, което търси политически ефект“. Убитият беше негов икономически съветник.
Изборът на момента за неговото извършване е целенасочена провокация и посегателство не само срещу обществения ред в страната, но и срещу усилията за постигането на членството на България в ЕС.
А тогавашният премиер Станишев видя умисъл, тъй като било след публикуването на критичния доклад на Европейската комисия за борбата с организираната престъпност и корупцията в България.
Политическите отношения на Кюлев обаче поставят под съмнение и решимостта на властите да разкрият престъплението. В дипломатически доклади от края на 2005 г., публикувани от WikiLeaks, американският посланик Джон Байърли отчита, че шест седмици след убийството не са иззети ключови материали, включително компютърът на банкера, телефонни разпечатки и банкови данни. Посланикът изказва подозрение, че разследването се спъва от страх финансовите отношения на Кюлев да не доведат до неудобни разкрития за високопоставени политици, включително Първанов.
Така политическото измерение се оказва двойно: властта вижда в убийството удар срещу държавата, а наблюдатели допускат, че отношенията на убития с нея пречат на разследването. Неизяснени остават и поръчката за смъртта му, и зависимостите приживе.
Румъния – конфликти за пари и имоти
В съседна Румъния например също има убийства на бизнесмени, но сред проверените случаи от последното десетилетие не се откроява подобна поредица от жертви с национална значимост и тежест в политическите среди.
Предприемачът Адриан Крайнер умира след нападение при грабеж в дома му. Корнел Диаконеску е убит, а обвинението е срещу неговия син. Сорин Ангел загива при конфликт на празненство. Дори атентатът с бомба срещу Йоан Кришан, бивш тъст на депутат от Националлибералната партия, води до обвинение срещу дъщеря му и предполагаем мотив, свързан с наследството. Публично известните разследвания сочат грабежи, семейни и имуществени конфликти.
Няма такава поредица от убийства на представители на едрия капитал и в други държави от бившия социалистически блок. В Чехия през октомври 2023 г. е убит Пшемисъл Холмик – строителен предприемач и кмет на Мислинка. Първоначално се проверява дали престъплението е свързано с бизнеса му. Разследването стига до бившата му съпруга и парите от наследството. През 2025 г. апелативният съд потвърждава 20-годишните присъди за нея и нейния полубрат.
Политическото положение на жертвата не превръща автоматично убийството в политическо. Но разкритото престъпление позволява тази граница да бъде установена.
В България тя остава размита от неразкритите убийства и неизследваните докрай зависимости. Докато няма отговор кой е поръчал изстрелите и защо, политическите връзки на жертвите са основателен предмет на разследване. Не доказателство, което го замества.
От Кюлев до Филипов
При Алексей Петров бизнесът, службите и политиката се пресичаха пред очите на всички. Застрахователният предприемач беше и съветник в ДАНС, а по-рано и барета в Специализирания отряд за борба с тероризма. Шестнайсет дни след разстрела му през август 2023 г. политическите му контакти отново станаха новина. Лидерът на ГЕРБ Борисов призна, че Петров е посредничил при разговорите между ГЕРБ и „Продължаваме промяната“, за да има правителство. До днес така и не е ясно кой го уби и защо.
През януари 2014 г. Европейската комисия отчита слаб напредък в разследването на над 150 поръчкови убийства в България с едно съществено изключение – делото „Килърите“. По онова време групата вече беше осъдена на първа инстанция.
В следващите 12 години броят на поръчковите убийства се е увеличил. Убийства като тези на Петър Христов и Алексей Петров поставят същия въпрос: кой поръчва смъртта на влиятелни хора и защо държавата не може или не иска да стигне до отговора?
Сега прокуратурата сочи спор за пари като мотив за убийството на Илиян Филипов. Ако бъде доказан, той ще обясни самото убийство, но няма да обясни отношенията, които смъртта на Филипов освети – с осъждан съдружник и с представители на властта. А те заслужават проверка независимо от мотива за убийството.
Политическото измерение е и в отговора на институциите: дали ще проследят парите и влиянието, или ще спрат при извършителя?
Announcing AWS Well-Architected Agent, an AI-powered intelligence to optimize your cloud environment (preview)
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/announcing-aws-well-architected-agent-an-ai-powered-intelligence-to-optimize-your-cloud-environment-preview/
Today, we’re announcing the public preview of AWS Well-Architected Agent, an AI-powered service that analyzes your AWS environment to deliver targeted, contextual recommendations for improving your applications’ cost, security, performance, and resilience. The AWS Well-Architected Agent analyzes your infrastructure, understands unique business goals, and delivers contextual recommendations with ready-to-implement fixes. It delivers context-aware optimization without relying on manual audits or generic checklists.
The agent evaluates your environment as an experienced cloud architect would. It automatically correlates utilization metrics, resource configurations, and application topology, and analyzes against Well-Architected best practices across 65+ AWS services. It generates recommendations aligned to your declared business goals, delivers implementation packages with every finding, and surfaces cross-pillar trade-offs making it simpler to remediate the findings.
Here are the three main features of this service:
- Goal-aligned intelligence: AWS Well-Architected Agent replaces flat, undifferentiated findings with context-aware, prioritized recommendations. You declare your business objectives and share your application context. The agent automatically generates and prioritizes recommendations by impact and effort against those goals.
- Three-level recommendations: AWS Well-Architected Agent provides individual resource findings with specific dollar impact (where applicable) and step-by-step remediation, consolidated findings across multiple resources scoped to your application, and broad architectural patterns and designs with Infrastructure as Code (IaC) code changes needed to align with Well-Architected best practices.
- Optionality in remediation: You can choose your path on how you want to remediate with a complete implementation steps tailored to your environment: the console walk-throughs, updated IaC changes for architecture-level recommendations, and AWS Command Line Interface (AWS CLI) commands.
AWS Well-Architected Agent in action
To get started, create an agent profile to define the scope of what Well-Architected Agent can access and provide recommendations on, complete the IAM role setup to access resources, conduct architecture review, and remediate recommendations.
Create an agent profile
In the AWS Well-Architected console, choose Get started with Well-Architected Agent. You can define an agent profile that specifies which AWS accounts and applications to monitor, which optimization pillars to focus on, and the permissions required.
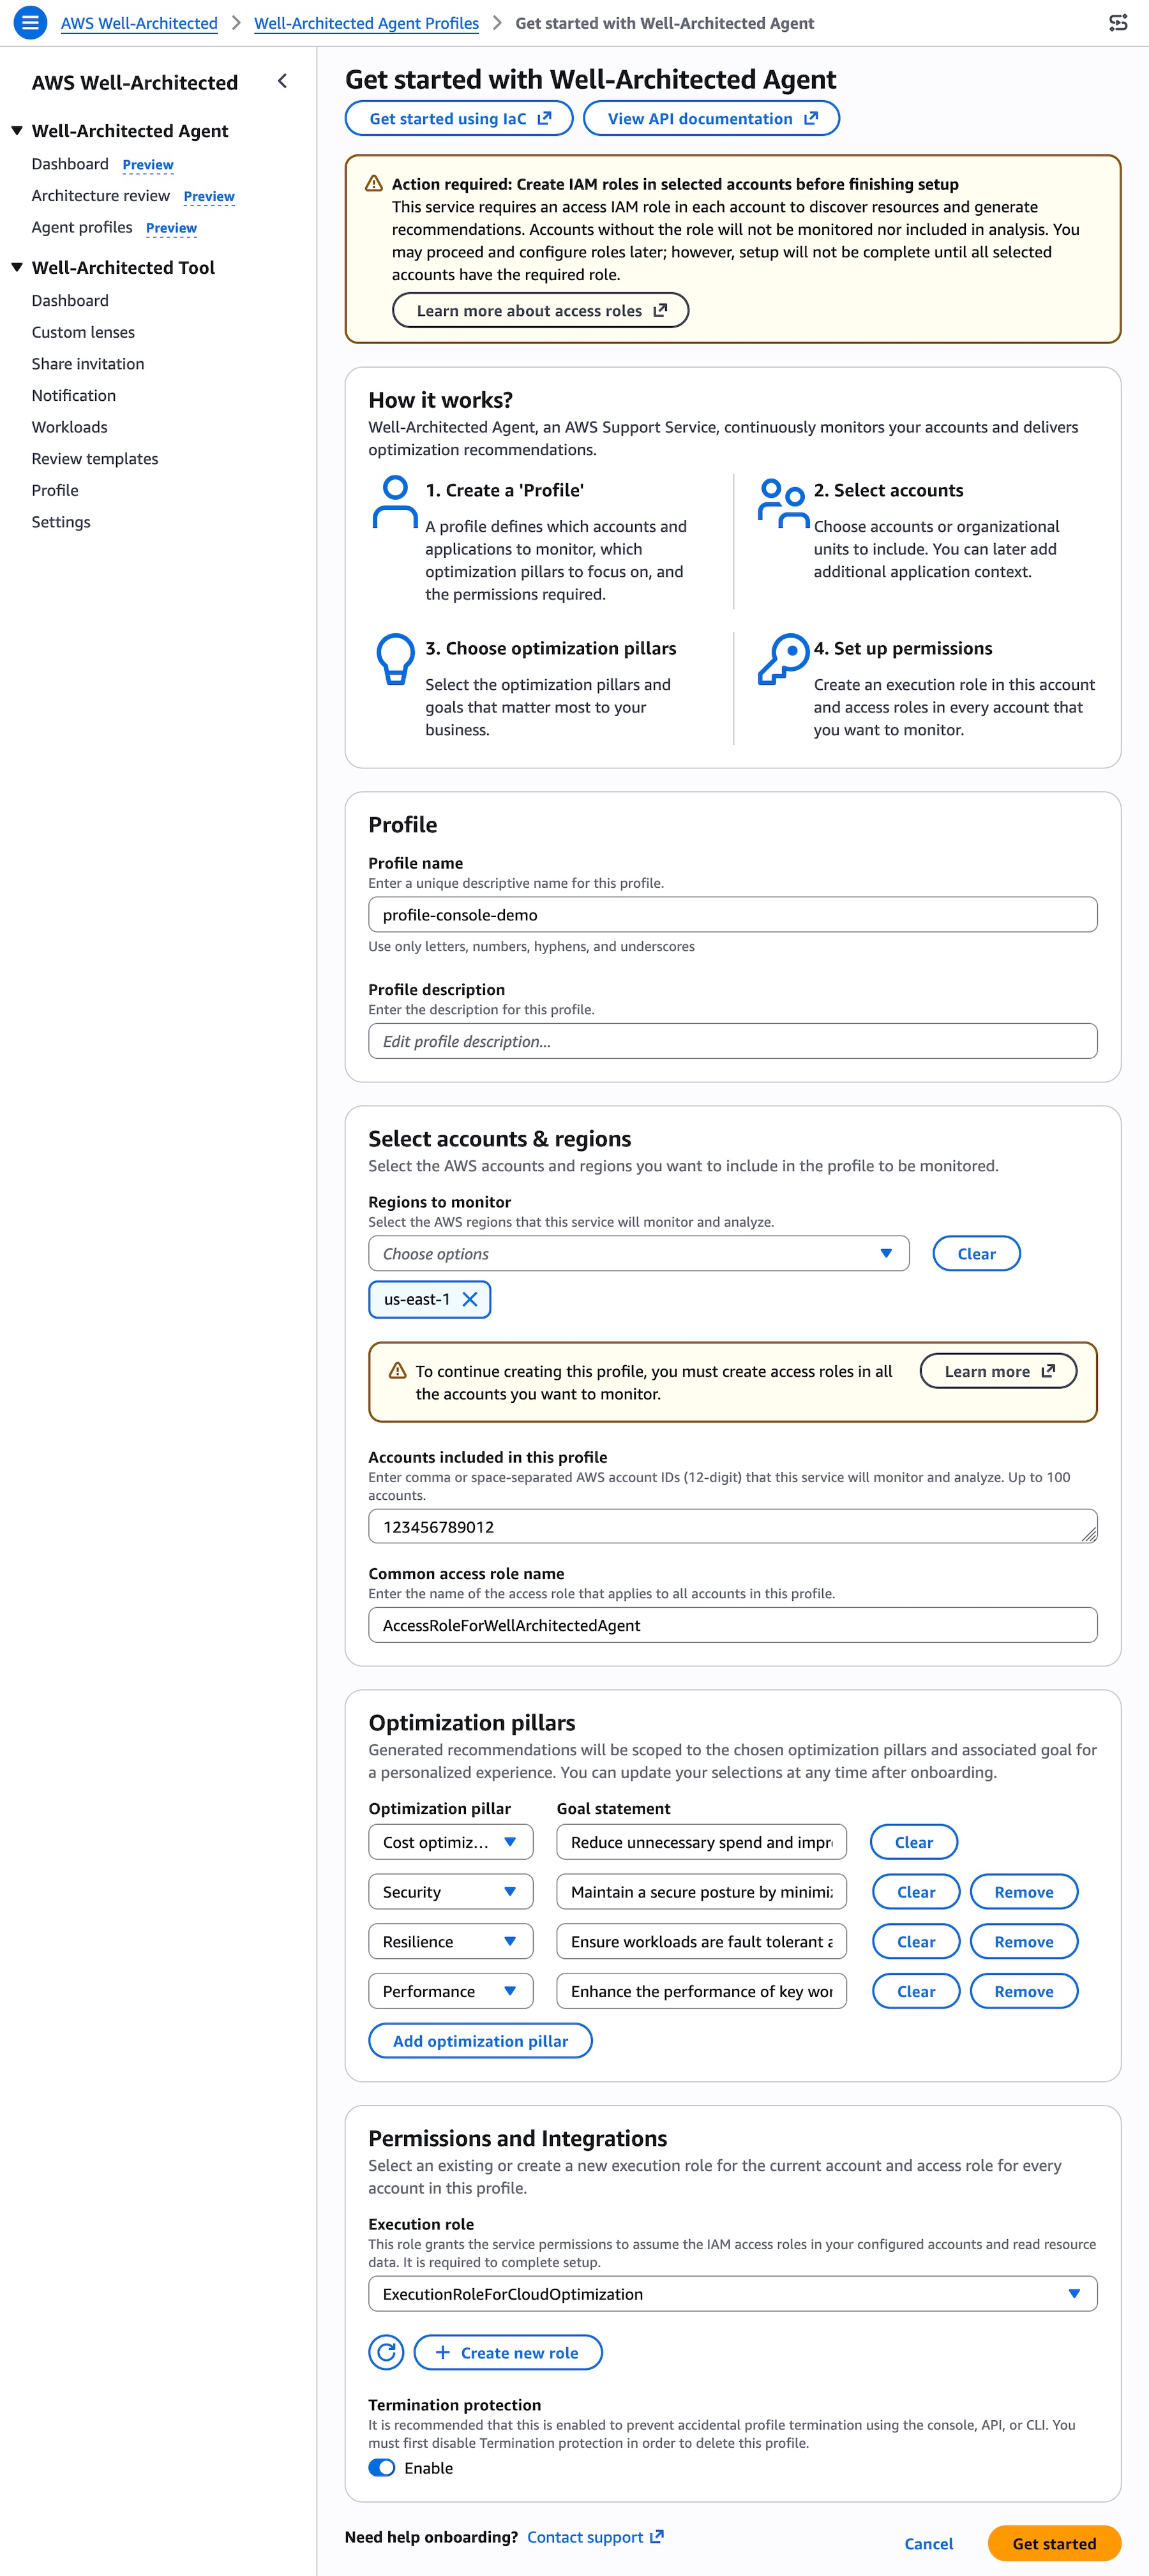
You can choose AWS accounts or AWS Regions to monitor and optimization pillars that matter most to your business. You can also set goals for each pillar: cost optimization, performance, resilience, and security.
To give access to the agent for your AWS environment, provision customer-managed IAM roles the agent uses to read resource configurations, utilization metrics, and application topology. To learn more, visit the IAM prerequisite for AWS Well-Architected Agent.
When you choose Get Started, the agent creates your agent profile. Resource and application recommendations will be generated within 24 hours after profile creation.
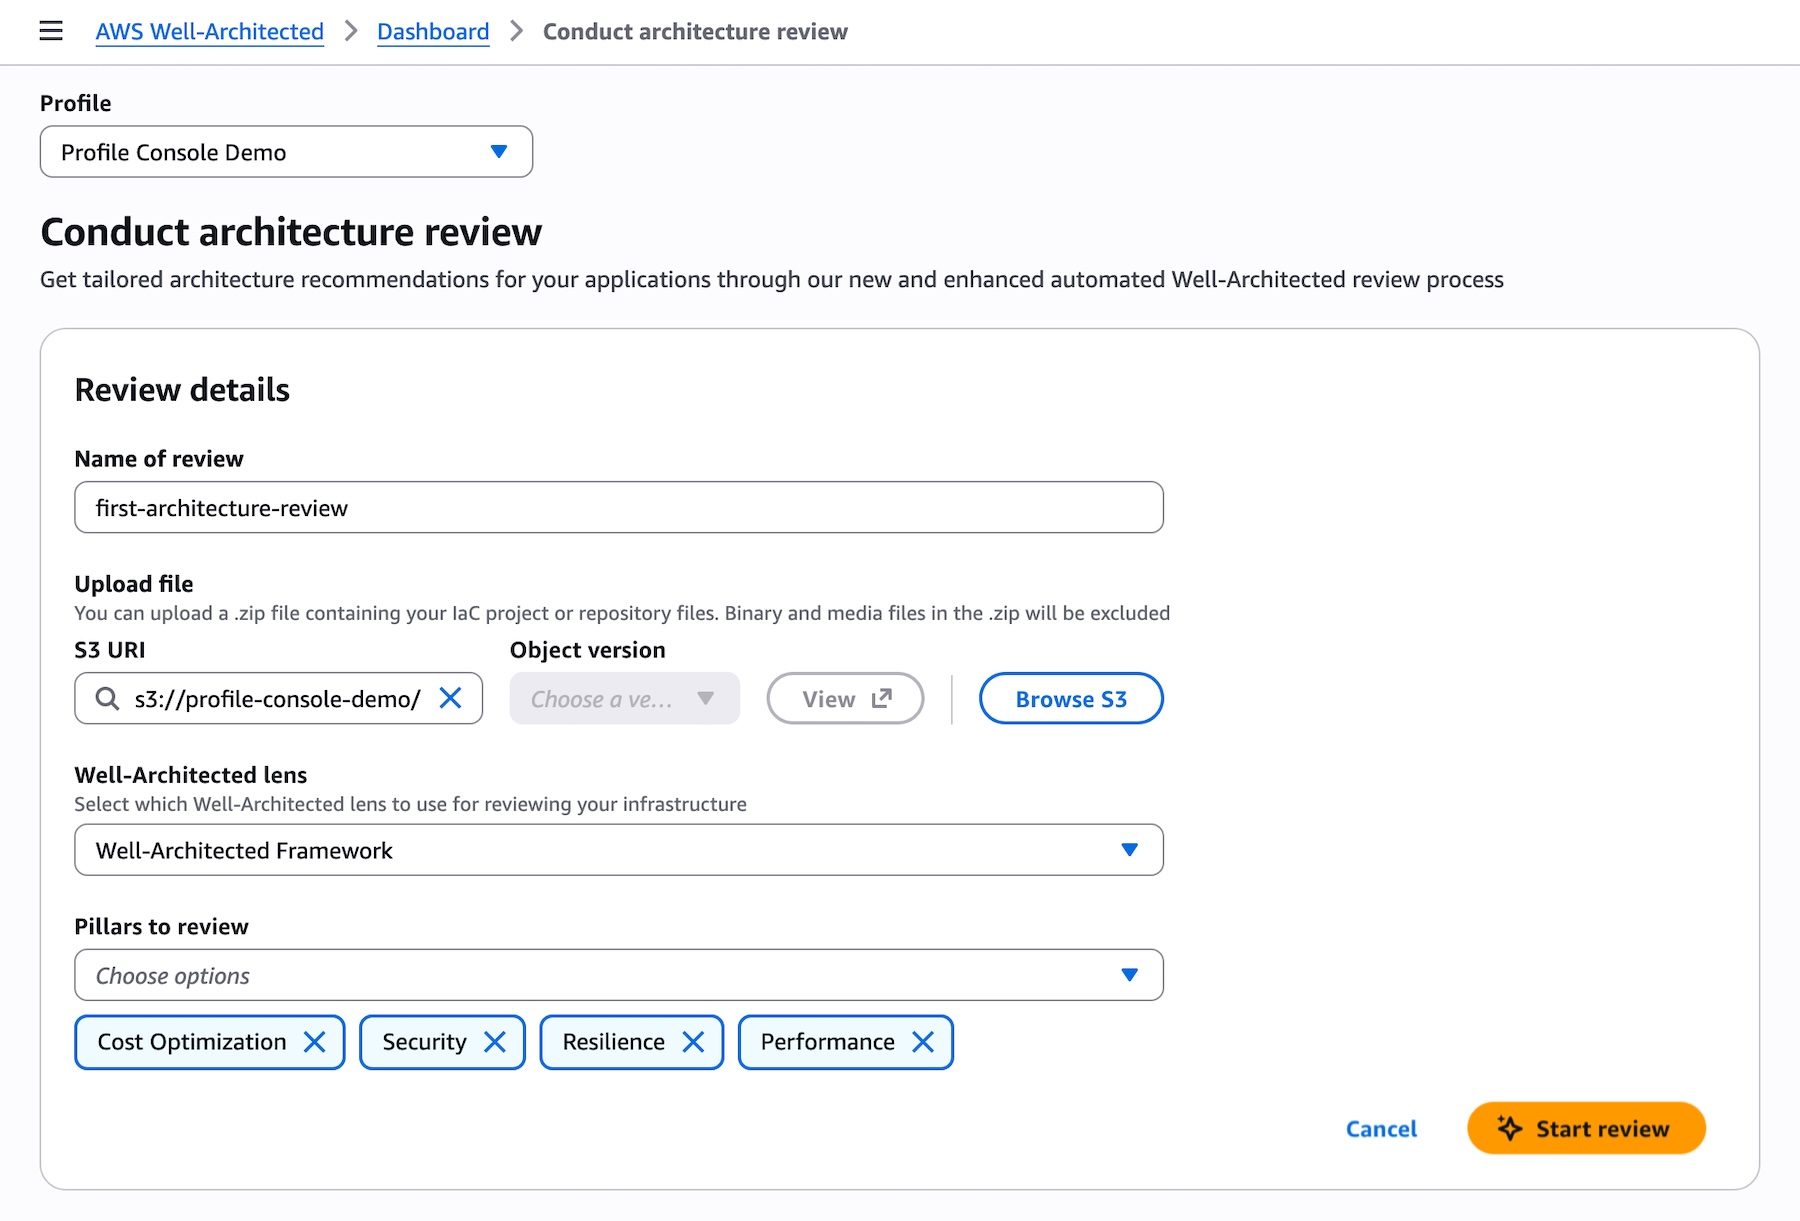
You can conduct an architecture review on pre-deployment workloads by uploading an IaC project in Terraform, AWS CloudFormation, or AWS Cloud Development Kit (CDK) to be analyzed. Choose Conduct architecture review in the dashboard, upload a.zip file containing IaC project or repository file, and select which Well-Architected lens to use for reviewing your infrastructure.
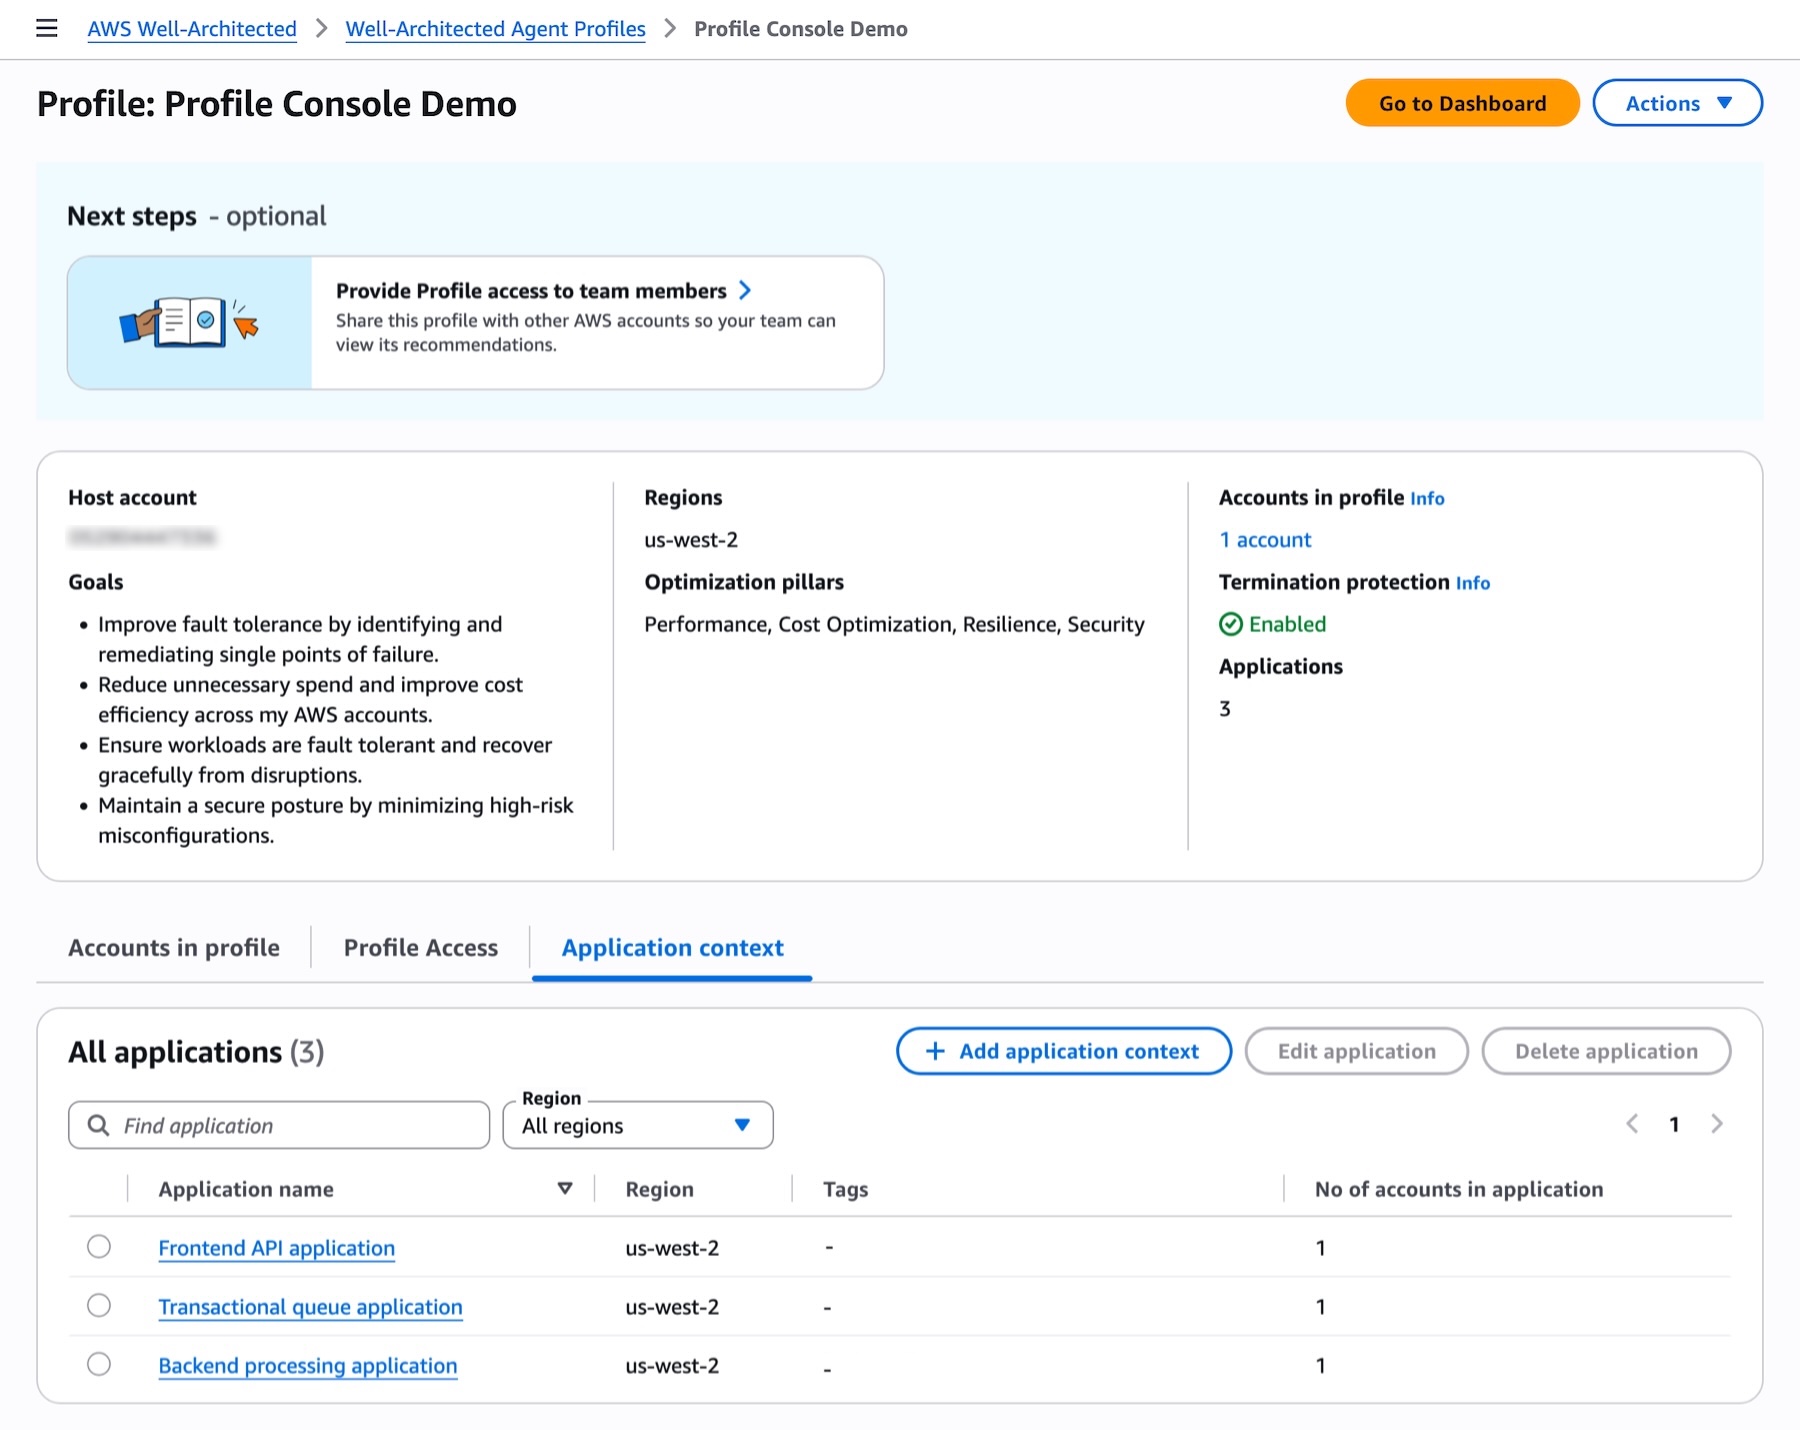
You can define your applications to add context which will enhance the relevancy and further contextualize recommendations. Choose Add application context in the dashboard, add your applications with AWS accounts, AWS Regions, AWS services, tags if you want to narrow the scope to specific resources, and the details of applications.
Review prioritized recommendations and start remediating
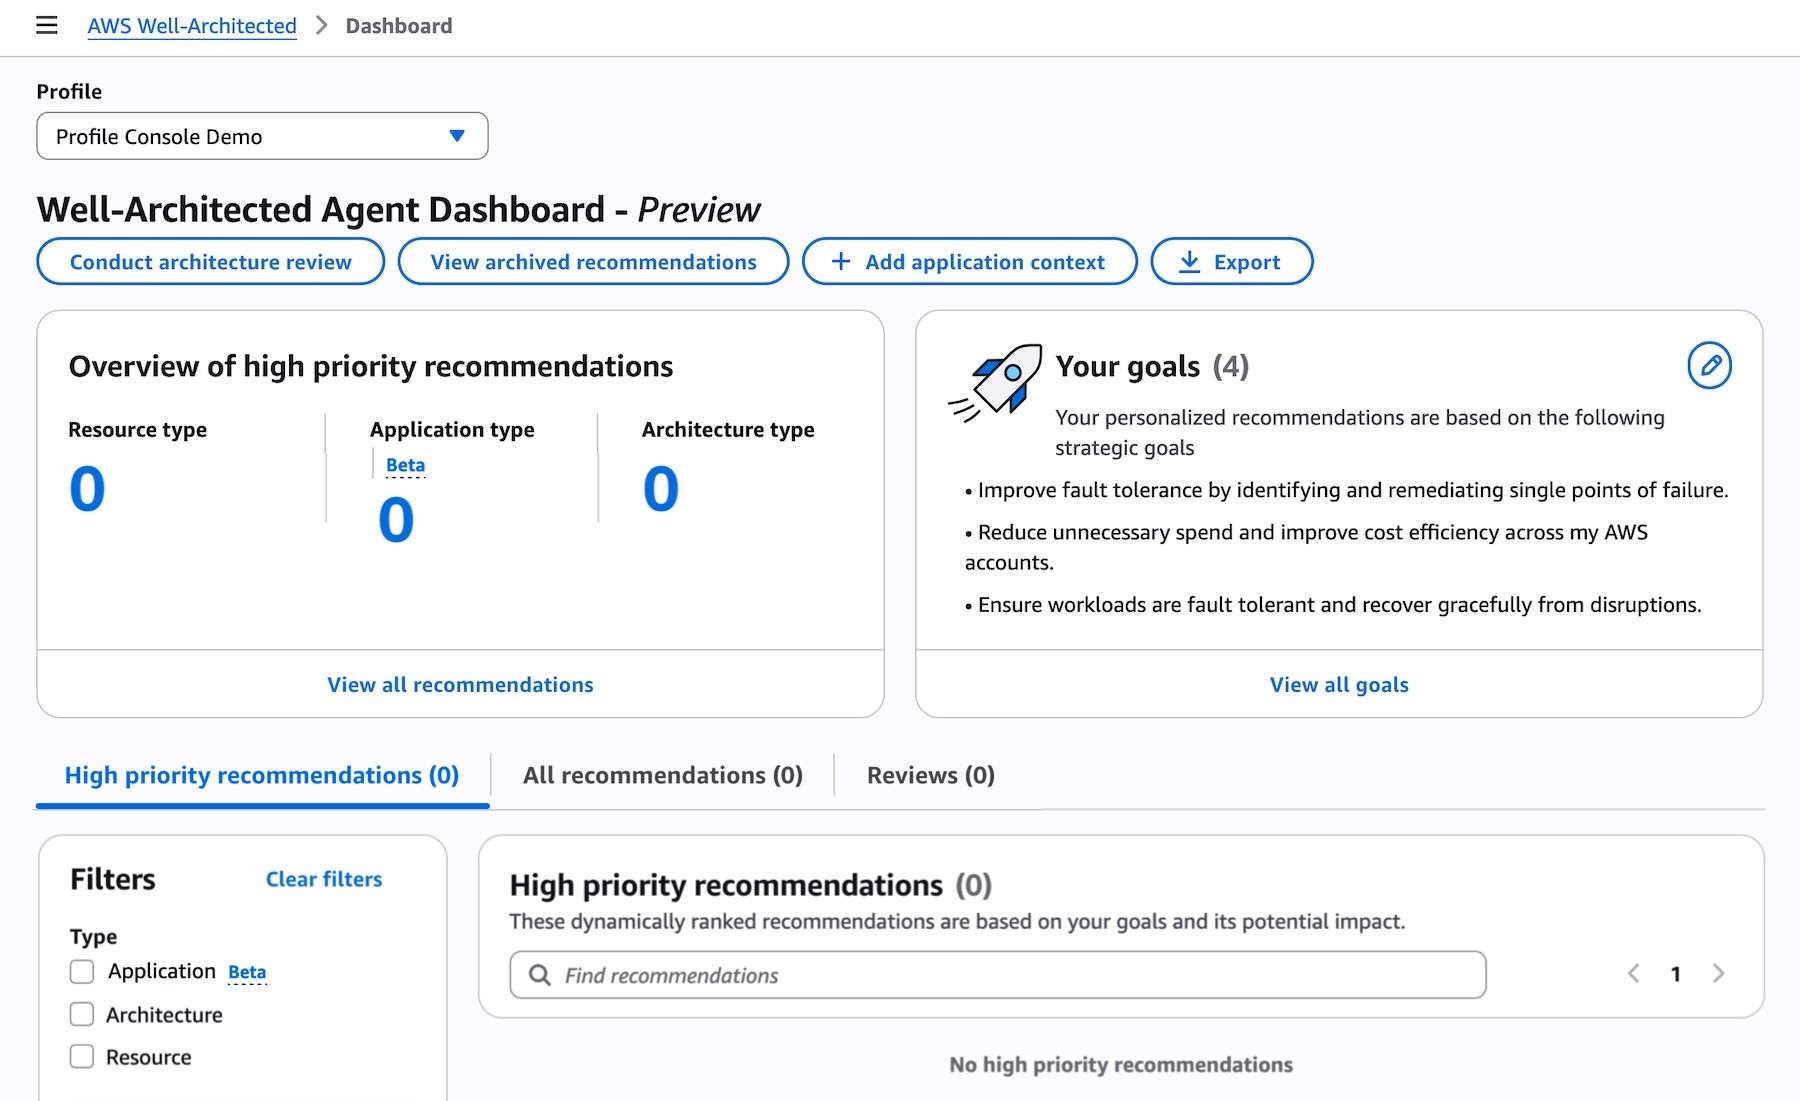
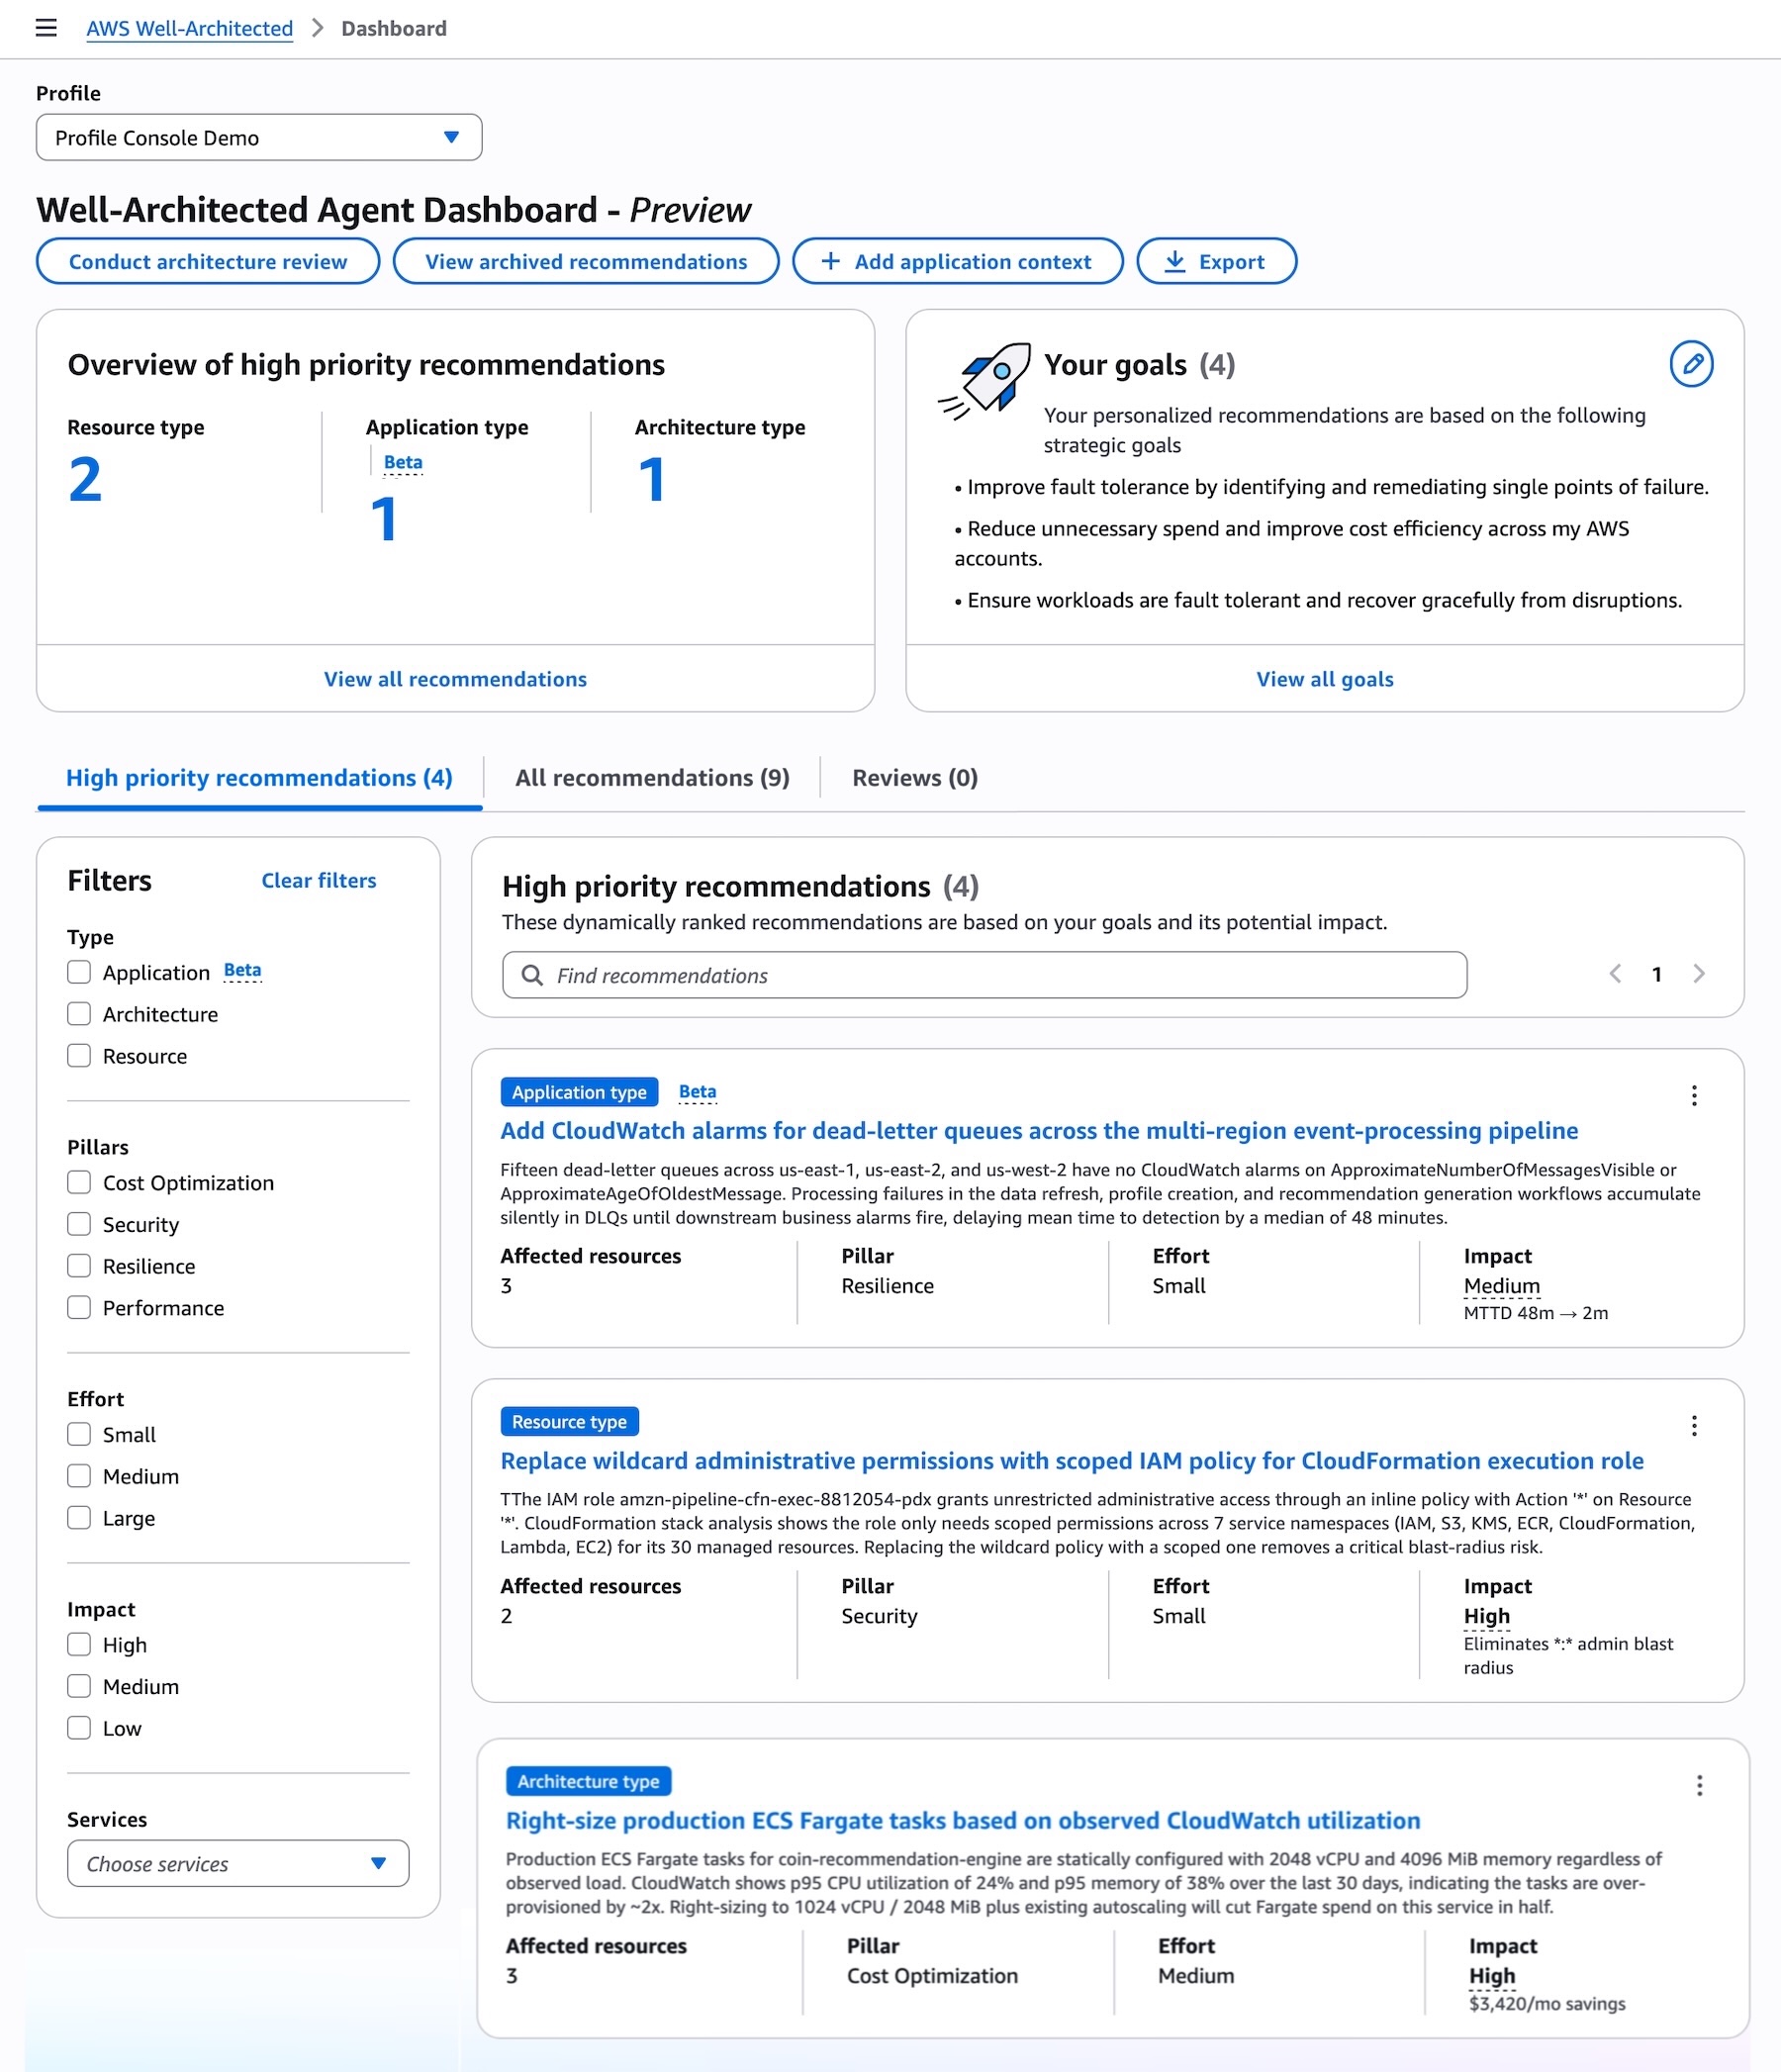
Now you can see generated prioritized recommendations generated by the agent across your resources and applications, selected pillars, ranked against your declared goals, with automation-ready remediation included.
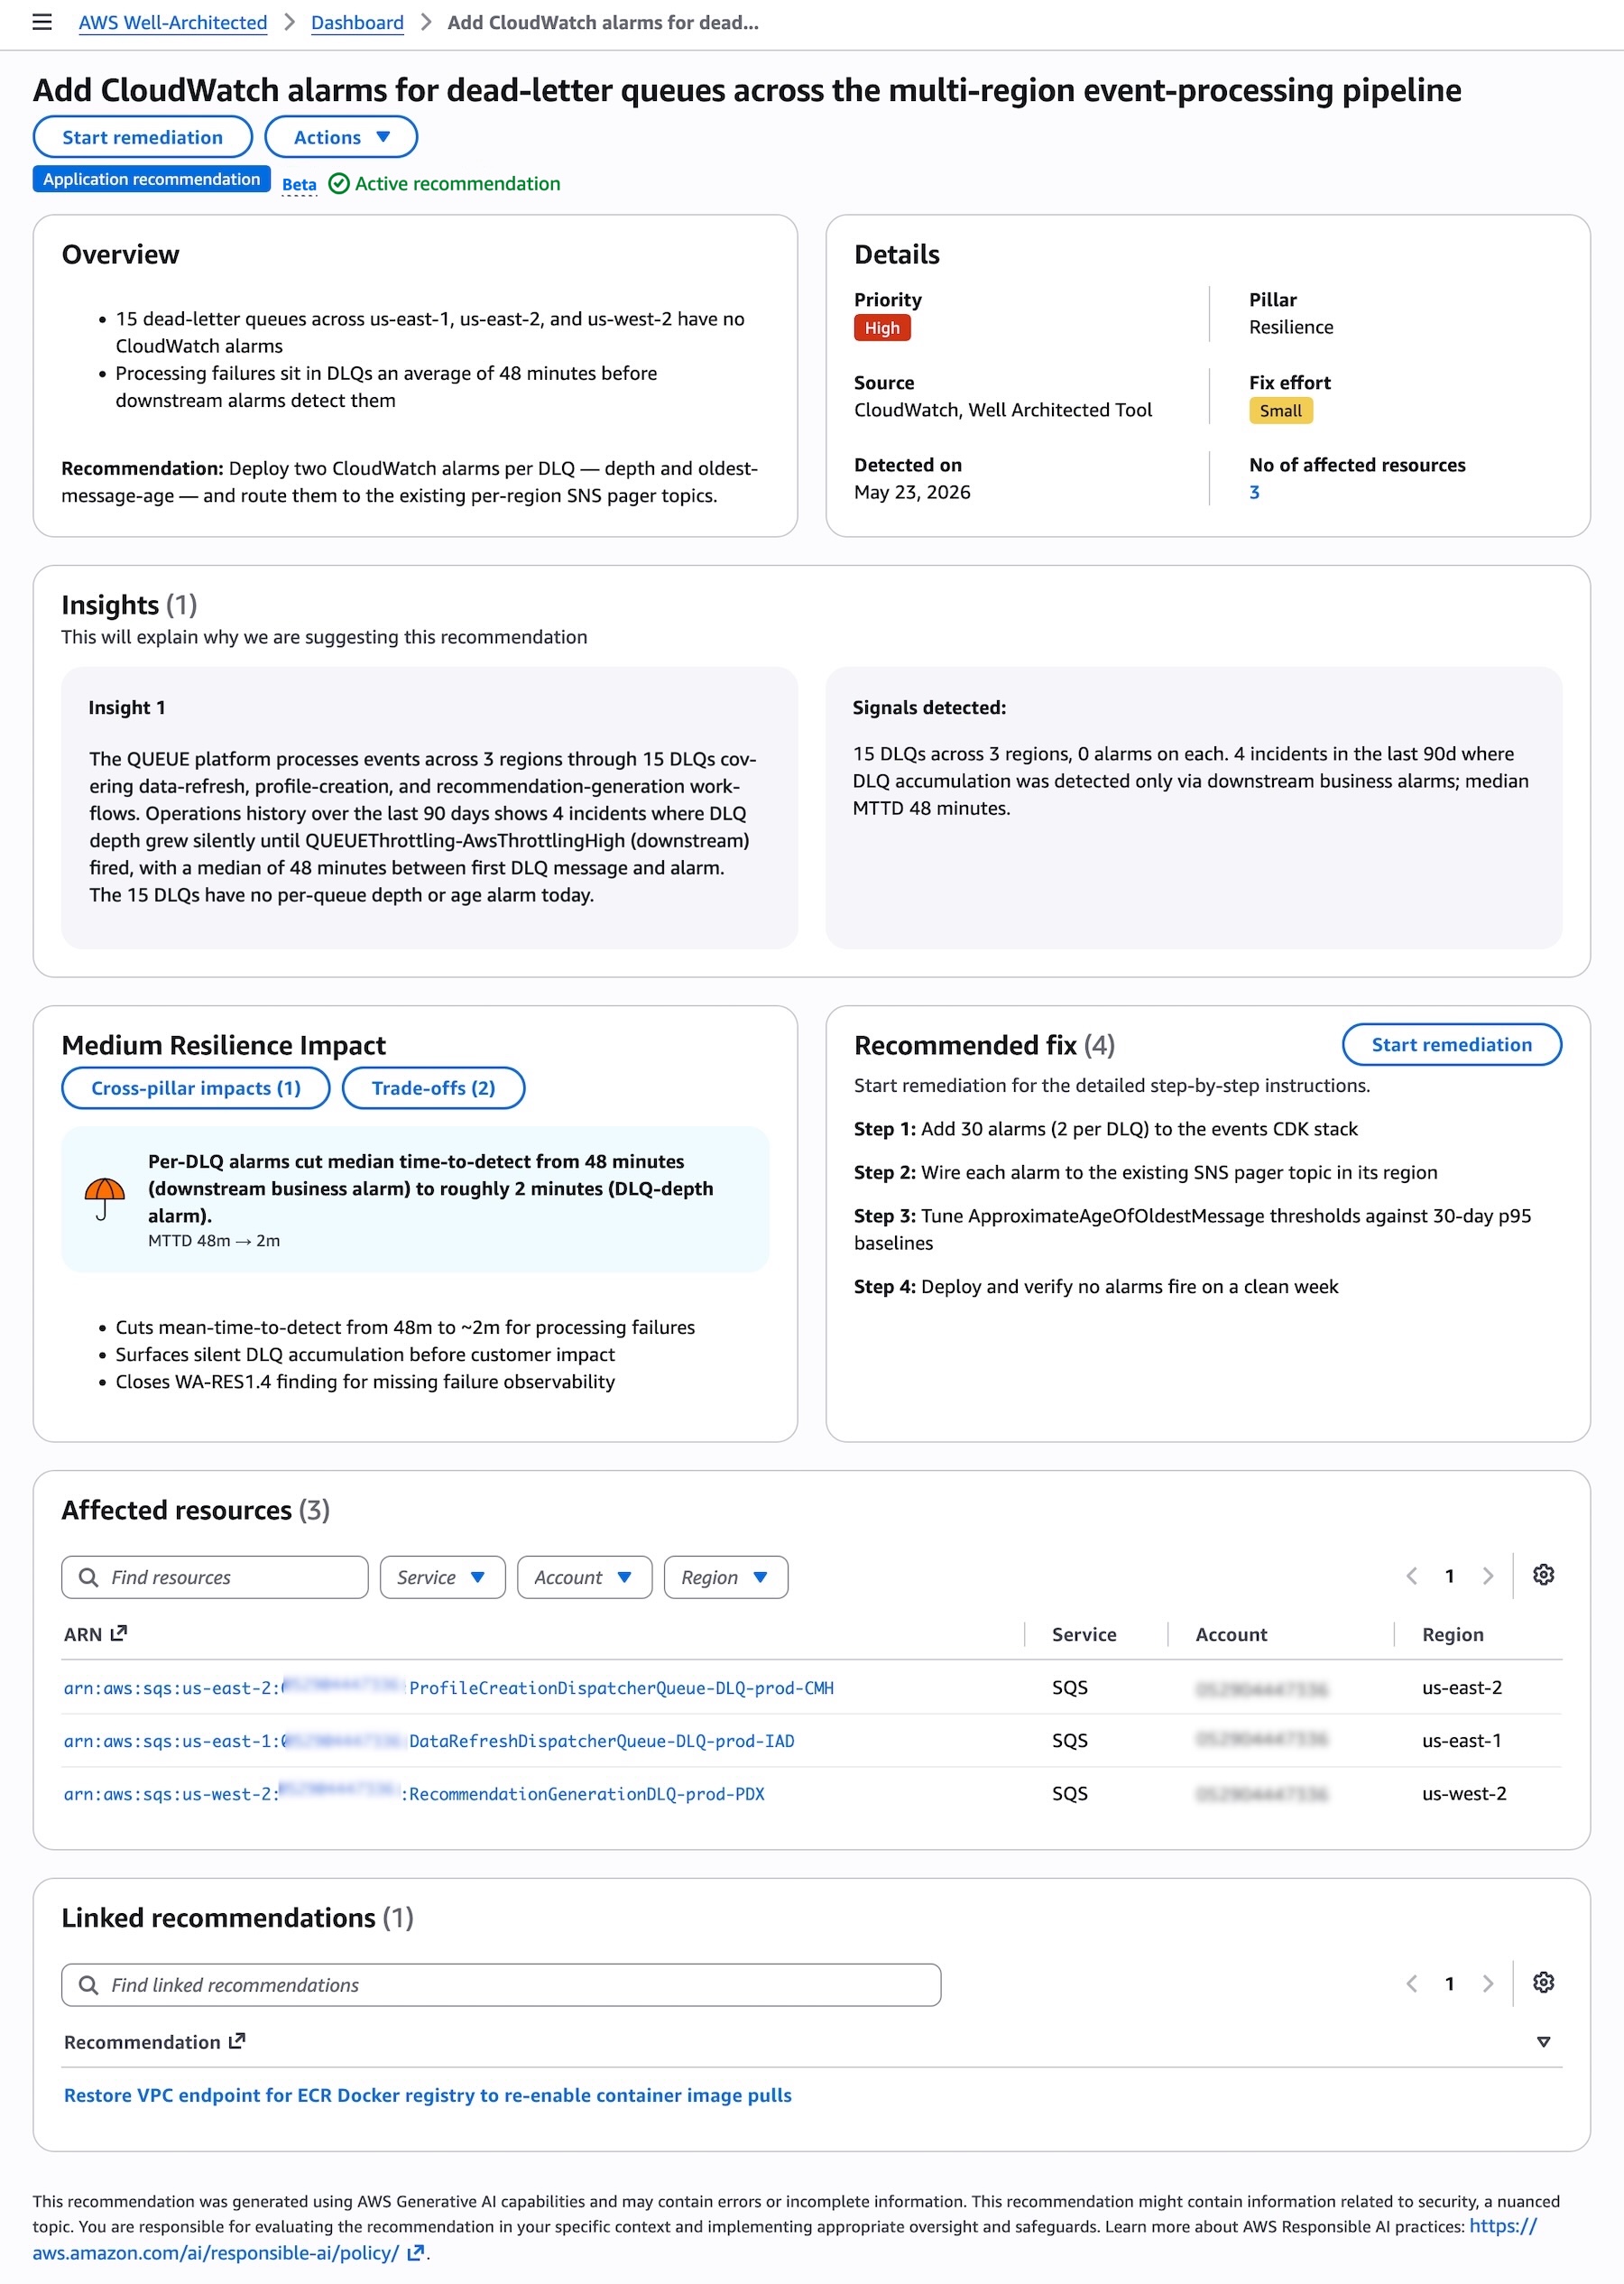
When you choose the specific recommendation, you can see the details, insights into why the agent are suggesting the recommendation, impacts and trade-off, and recommended fixes across affected AWS resources.
Choose Start remediation to address recommended fixes. You can choose the console, updated IaC template, CLI commands to remediate by the resolution type. It provides detailed step-by-step instructions and you can roll out this instruction and verify the result.
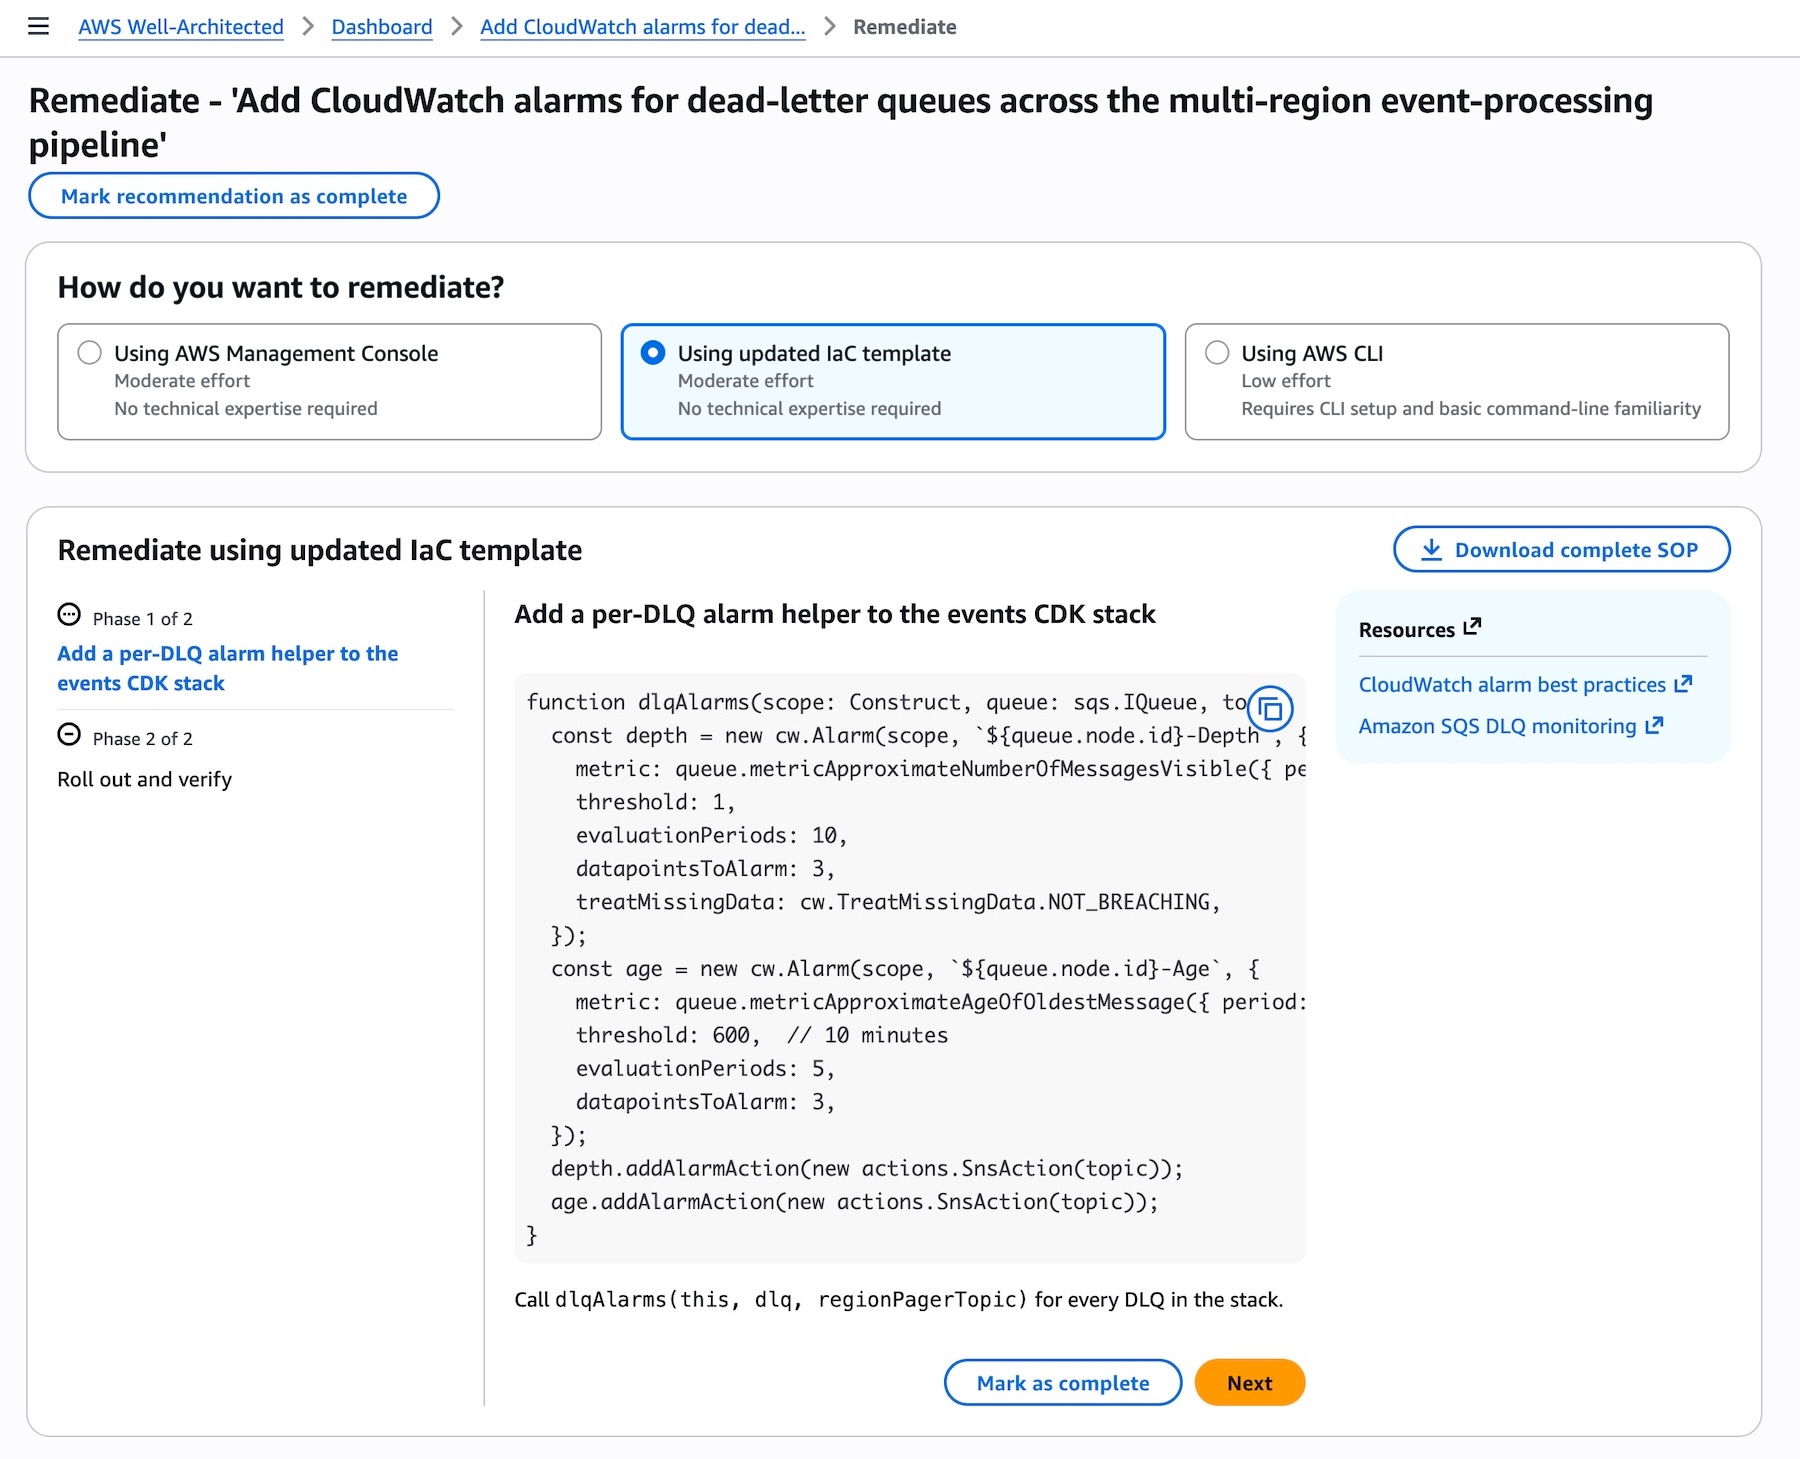
When you choose Using updated IaC template, the agent provides the code changes needed to update your existing IaC templates such as the CDK function shown above which you can copy directly into your codebase.
You can also configure API access to integrate recommendations directly into your existing development and operations workflows. To interact with the agent programmatically, including calling APIs and searching documentation, try the AWS MCP Server and plugins with your preferred AI coding tool. To learn more, visit the AWS Well-Architected Agent documentation.
Things to know
Here are some things that you should know about the Well-Architected Agent.
- Automation: You can receive recommendations with the exact IaC code changes needed to remediate, with risks identified by pillar, catching issues before they reach production. Recommendations are delivered through the console and API so you can act without context-switching. Recommendations are also updated periodically, so new recommendations are available for your team to track regularly.
- Evaluation: Generative AI capabilities produce this recommendation, which may contain errors or incomplete information. You are responsible for evaluating the recommendation in your specific context and implementing appropriate oversight and safeguards. Learn more about AWS Responsible AI practices.
You can still use existing AWS Well-Architected Tool to manually evaluate your cloud architecture with user-defined lenses that measure your workload using your own best practices.
Join the preview
Access to the AWS Well-Architected Agent and its recommendations is available in US East (N. Virginia), US East (Ohio), and US West (Oregon). You can onboard workloads from any AWS commercial Region. AWS Well-Architected Agent is delivered by AWS Support and available to AWS customers with an AWS Support plan.
Give it a try today in the AWS Well-Architected console and send feedback through your usual AWS Support contacts.
— Channy
Touring the F5 BIG-IP Next for Kubernetes Lab to Make AI Clusters More Efficient
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/touring-the-f5-big-ip-next-for-kubernetes-lab-to-make-ai-clusters-more-efficient-nvidia-dpu/
We checked out the F5 lab getting over 3x the performance from the same GPU cluster using F5 BIG-IP NEXT for Kubernetes
The post Touring the F5 BIG-IP Next for Kubernetes Lab to Make AI Clusters More Efficient appeared first on ServeTheHome.
Lula & Brazil Elections #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/ORyjaglQkxM
How Gerrymandering Can Splinter Neighborhoods
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/m9MZu7rKYq8
„Сан Себастиан 2026“. Нежността се завръща на екрана
Post Syndicated from Нева Мичева original https://www.toest.bg/san-sebastian-2026-nezhnostta-se-zavrushta-na-ekrana/
На хората им се обича. Истината е насъщна. Хуморът е вид милосърдие. За 24-ти път в живота си гледам кино до пресита в баския град Сан Себастиан на един от най-старите европейски фестивали и се старая да изведа свързващи нишки и повтарящи се мотиви. Смърт на роднина, отбелязвам, поезия; приятелство; емпатия. И още: колко е скучна дълбоката замисленост в близък план. Или: моля ви, имайте мимика.
От 263 заглавия от 47 държави едва смогвам да избера 40: всички премиери от основния конкурс плюс 23 истории, представени за първи път другаде от януари насам и селектирани сега в разделите „Латинохоризонти“, „Перли от други фестивали“, „Нови режисьори“, „Отворено пространство“. Опитвам се да хвана настроението на света. И с изненада установявам, че през 2026-та фокусът редовно е върху семейството, а най-често споделената необходимост сякаш е от откровен разговор. Дали заради, или въпреки това (винаги може да се поспори доколко човешките ни потребности съвпадат с културните), тазгодишното издание е далеч по-удовлетворително от доста предходни.
От 18 до 27 септември Златната раковина си оспорваха 17 творби от 12 страни, от които само 5 – на режисьорки. Вярно, това е повече от една на 20 кандидати за Златния лъв на последната венецианска „Мостра“ например, но си остава знак за определени липси. (Да видим какво в този смисъл ще се промени от 2027-ма: след 15 добри години начело на фестивала директорът Хосе Луис Ребординос предава щафетата на своята заместничка и за първи път в 74-годишната си история най-важният испански филмов форум ще бъде оглавен от жена: родената в Сан Себастиан Маялен Белоки, доктор по кинознание.) Така или иначе,
в епицентъра на най-интересните екранни събития се оказаха изключително героини.
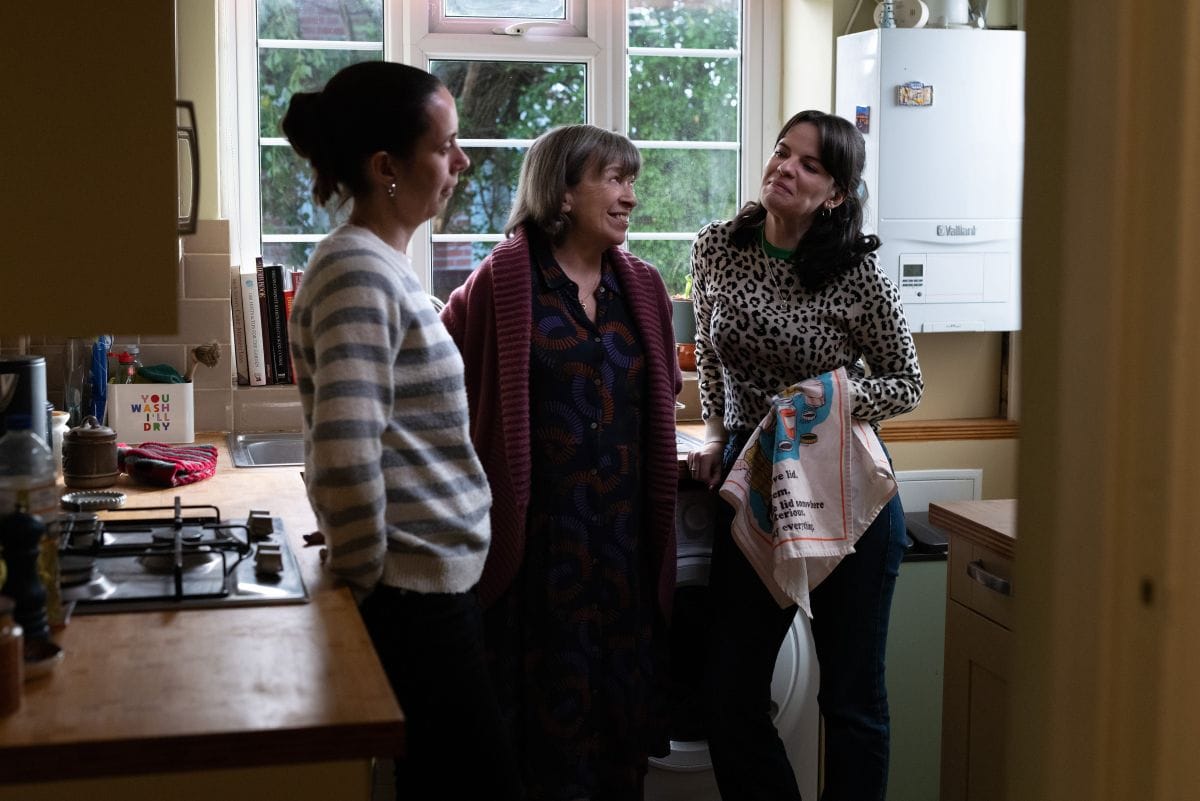
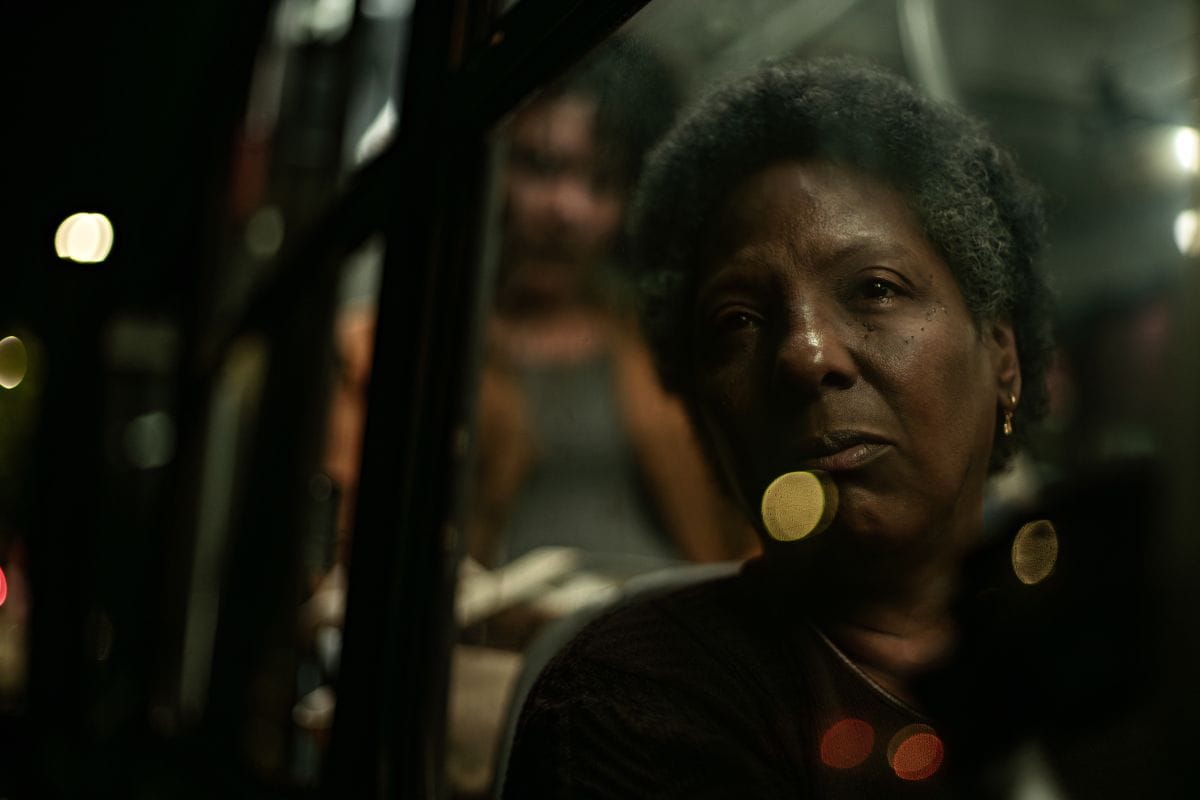
Кейт О’Флин, Марион Бейли и Алис Бейли Джонсън в „Любов и грижа“ / Режани Фария в бразилския филм „Висентина моли за извинение“
Жени поправят и проправят
При мен импровизацията има огромен дял в еволюцията на персонажите и на отношенията им: не че се отклонявам от сценария през импровизацията – сценарият ми произлиза от нея,
каза Майк Лий на журналистите след прожекцията на своя филм „Любов и грижа“ (Tender loving care), който няколко дни по-късно получи именно наградата за сценарий, Златна раковина за най-добър филм и Сребърна раковина за главната роля на Кейт О’Флин (същата, която неотдавна спечели „Еми“ за сериала „Заливът на вдовицата“).
„Любов и грижа“ започва и завършва със свръхблизък план на лицето на възрастен мъж: камерата поставя чуждия човек право в личното ни пространство, там, където обикновено са най-скъпите ни, и ние, щем – не щем, го разпознаваме. И не спираме да разпознаваме като свое всичко до края… Две най-добри приятелки заживяват в една квартира и трябва да се справят не само с ежедневието си на социални работнички, но и с лош обрат в дома на родителите на едната. Налице са всички елементи за тежка драма и е възхитително как майсторски Лий и неговите съмишленици сглобяват от тях комичен разказ, който не бяга от страшното, не унижава героите си, не тероризира зрителите.
Човечността не е изчезнала, нищо че времената са трудни. Този филм не бива да се разбира като романтичен ескейпизъм: той говори за нещо много реално – съчувствието,
добави авторът на пресконференцията, на която се появи само във видеовръзка. И потвърди, че поради болест и съпътстващите я трудности това може да е последното му киноначинание. Нещо подобно обаче се чу и през 2024-та, покрай предишната му творба „Горчиви истини“, която – пределно напрегната и безнадеждна – щеше да е тъжен кариерен финал. Да се надяваме, че ни чакат още много любов и грижа от Майк Лий.
Елементите, от които е създаден „Висентина моли за извинение“ на бразилеца Габриел Мартинс (втора незаобиколима премиера от „Сан Себастиан 2026“), също са тези на тежката драма, а въздействието – също окриляващо. Докато Лий ползва за антидот на баналността и мъката огромни дози игривост, у Мартинс спасението идва чрез разнообразието: човешки поведения, ситуации, интериори и екстериори, които са пиршество за окото и за ума. Висентина е майката на шофьор, който – изглежда – нарочно е предизвикал катастрофа, за да отнеме живота си заедно с този на цял автобус непознати хора (сюжет, заимстван от злощастния случай с пилота на „Джърмануингс“ отпреди десетилетие и съпоставим в киното с този на „Трябва да поговорим за Кевин“). Жената усеща нужда да поеме отговорност и започва да се среща с близките на другите жертви, за да им поиска прошка.
Да, двата часа и половина може би идват в повече за способността на зрителите да съпреживяват интензивно и да, завършекът криволичи, но органичната игра на актьорите, дълбоко хуманната идея статистиката да бъде разглобена на личности плюс финото разбиране на автора за „социалния пърформанс“ (както нарече той липсата на прямо общуване по щекотливи теми) правят от „Висентина моли за извинение“ преживяване, което белязва.
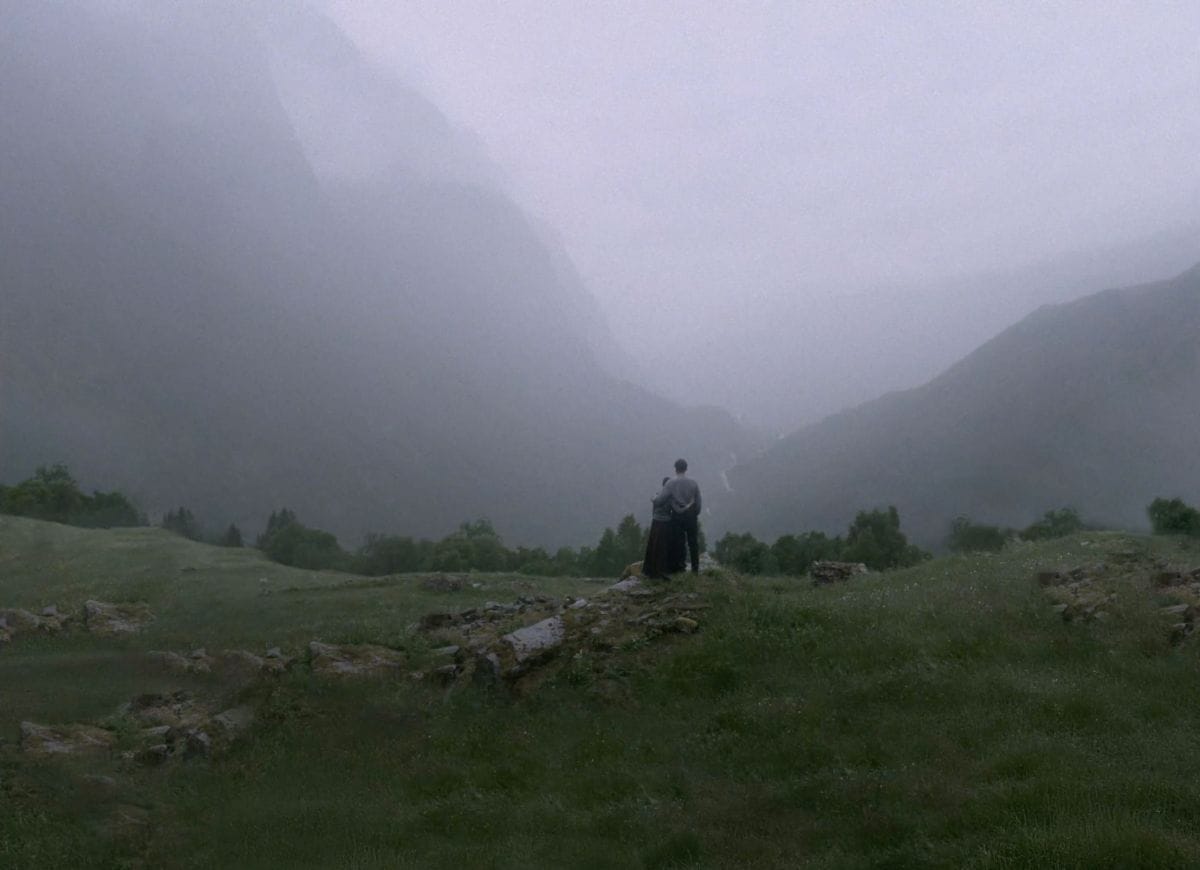
„Благодатта на земята“ на Ханс Петер Мулан започва с две ръце, които загребват пръст и сняг. В красива, но неприветлива пустош млад мъж, за чието минало и принадлежност няма да научим нищо, се мъчи да оцелее. Към опитите му се присъединява млада жена със „заешка уста“. Исак и Ингер започват да си помагат, да си допадат, да са заедно и всяка пречка да превръщат в стъпало. И нещата потръгват. Клетото им убежище в скалите прераства в колиба, а с годините – и в благоденстваща ферма. Двамата полудиви странници стават двойка и пълнят земята, и обладават я, и господаруват. Множат се притежанията им, децата, знанията. Но със знанията (и новостите, и отклоняването от привичките – все по почин на жената) расте и тъгата. Райската градина, която се е опитала да погуби Адам и Ева, се превръща в райска градина, чиято гибел те неволно отключват.
Дълбоко патриархалната постановка на тази 180-минутна екранизация по едноименния роман на нобелиста Кнут Хамсун, библейските препратки, романтичната (и подвеждаща) тяга към прединдустриалното общество – нищо от това не натежава в ущърб на великолепното произведение, което справедливо беше удостоено с награда за операторското майсторство на Оскар Далсбакен и със Сребърна раковина за главната роля на Аста Кама Аугюст (отличие, споделено с Кейт О’Флин от „Любов и грижа“).
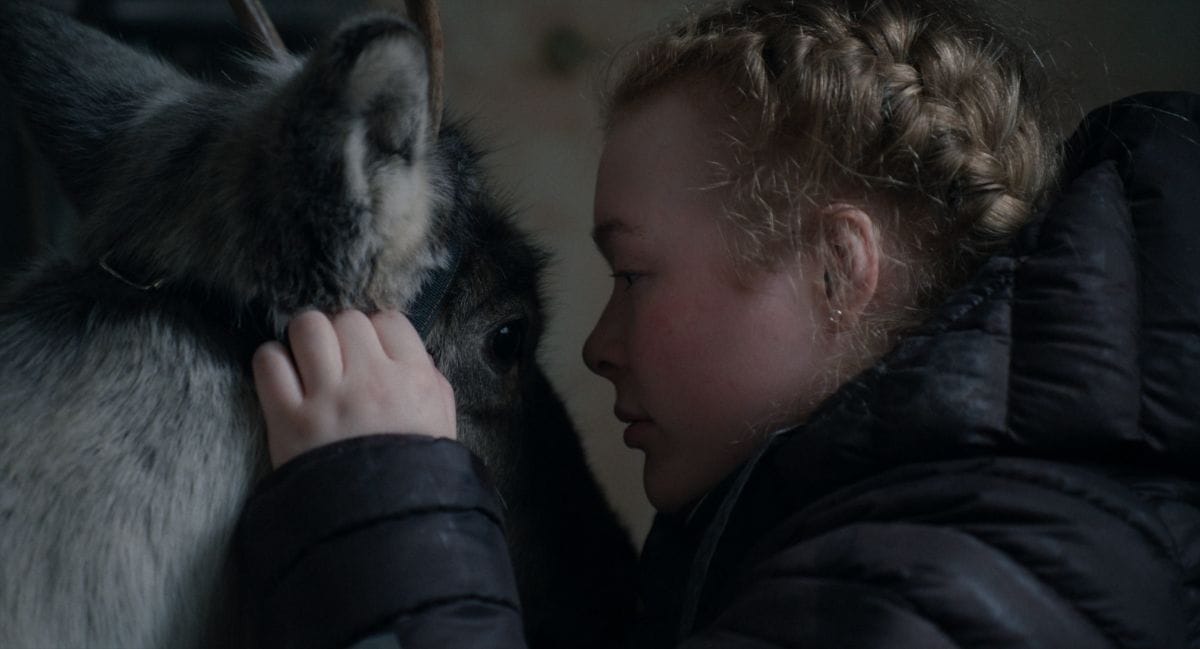
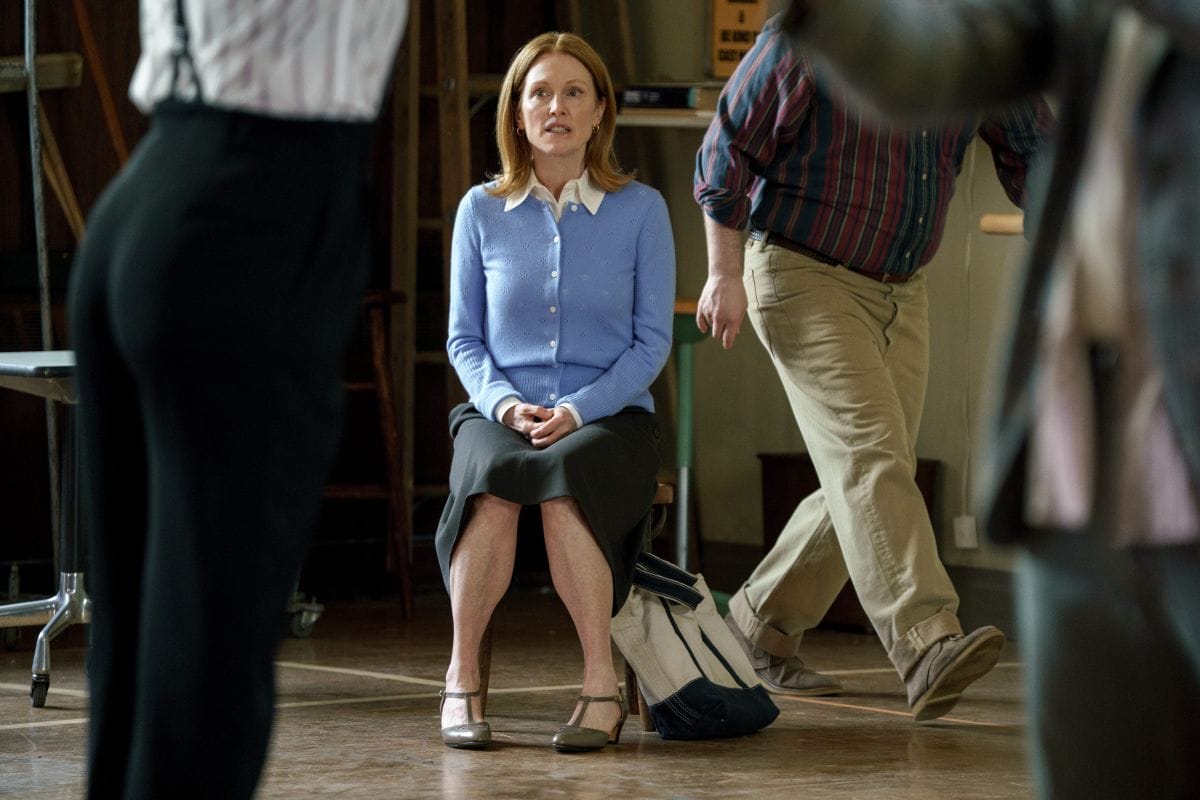
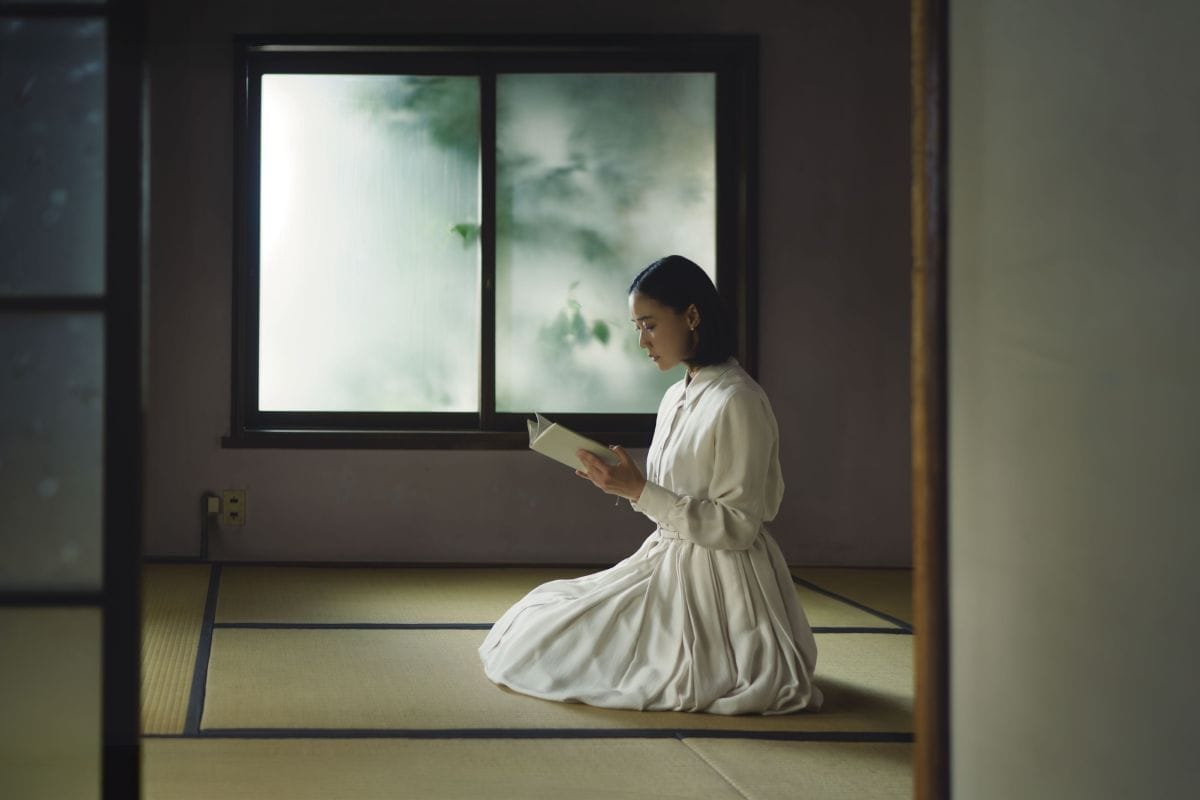
Ани-Кристина Юсо в „Ледена земя“ на Аманда Кернел / Джулиан Мур в „Дебютът“ на Джеси Айзенбърг / Ю Аои в ролята на Сатоми от „В стаята на баща ми“
Сребърна раковина за режисура взе Аманда Кернел за „Ледена земя“ (оригиналното Garrat du váimmu означава нещо като „Сърцето ти плаче“, но бидейки копродукция между няколко северни страни и България, филмът вече си има определено българско заглавие). Саамско момиче наследява стадото елени на баща си и смело, но безуспешно се опитва да се докаже в изключително мъжката общност на еленовъдите. Историята на нейното поражение, което посвоему се оказва победа – сдържана, понятно изложена и увлекателна за гледане и слушане (с много ласкави близки планове и един вълнуващ йоик) – не е толкова предсказуема, колкото изглежда, че ще е. И макар да губи ритъма си във втората половина, оставя усещане за радост.
С кинодебют в официалната селекция участваше и 64-годишната японска писателка и кураторка Маха Харада. „В стаята на баща ми“ е екранизация по собствения ѝ разказ „Ненужен мъж“: пазителка в музей губи любимата си работа, обаче получава компенсация от съдбата – плик с ключ, адресиран до нея от вече покойния ѝ баща; среща с човек, който го е познавал по-добре от самата нея; признание за труда си от малословен колега. Съдържанието е толкова ефирно, че на моменти изглежда аморфно. Но докато свръхексплоатирани японски съставки (чаена церемония, сакура, дълбоко потисната емоционалност) се смесват с такива от Запада (Пучини, Белини, Ротко) и с малко самотни, изящни стихове, тук и там звънва по някоя наистина прочувствена струна.
В „Дебютът“ – друг кандидат за Златната раковина – Джеси Айзенбърг, който преди две години блесна с трагикомичния си филм „Истинска болка“, е вече не „само“ актьор, сценарист и режисьор, но и автор на музиката и текста на мюзикъла, около който се върти действието. Джулиан Мур е богата домакиня със закърняла личност, която се явява на прослушване за малка роля, а Пол Джамати – взискателен режисьор на любителски представления в Ню Йорк. Бъбривата хумореска е съвсем предвидима и без принос към растящото множество от филми, занимаващи се с терапевтичната сила на театъра (Ghostlight е последното попадение по темата, което ми е известно), а Мур сериозно преиграва.
И все пак авторът е безспорен талант. И – нещо, което едва ли ще си проличи точно в „Дебютът“, но за което държа да изразя уважение – алтруист. В края на миналата година Джеси Айзенбърг (току-що отказал да играе Марк Цукърбърг от морални съображения) дари бъбрек на непознат. Каква е връзката с творчеството му ли? Всякаква.
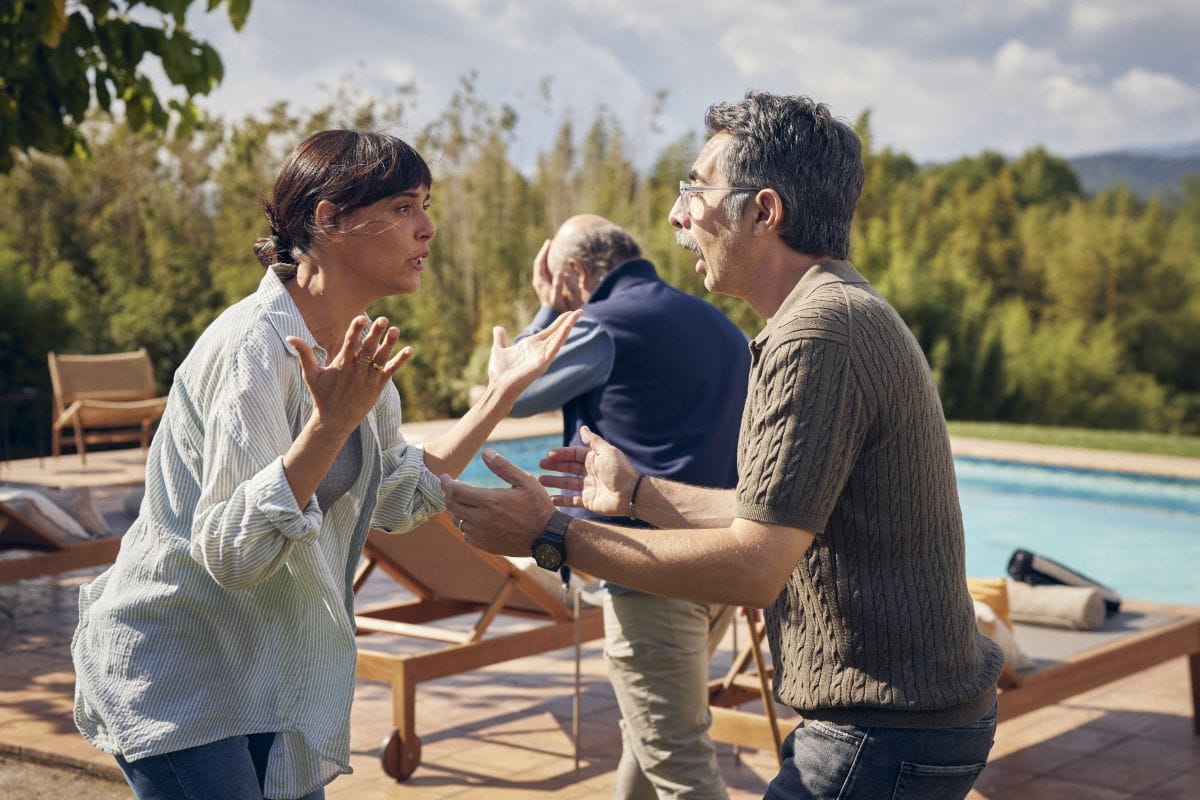
„Още пет минути“: Белен Куеста, Хавиер Камара и Берто Ромеро / Сцена от „Лошият баща“ с Едуард Фернандес в централната роля / Мерсѐдес Мора̀н в „Тъжните ми мъртъвци“, реж. Пабло Лараин
Колективни лудости
Два силни испански филма за дисфункционални семейства направиха фурор в конкурса – „Още пет минути“ на Хавиер Руис Калдера и „Лошият баща“ на Роберто Буесо. За първия Хавиер Камара (санитарят от „Говори с нея“) беше награден със Сребърна раковина (в Сан Себастиан няма „мъжки“ и „женски“ отличия, а само за главна и поддържаща роля, както е в случая), а вторият, колкото и да заслужаваше, не беше зачетен от журито.
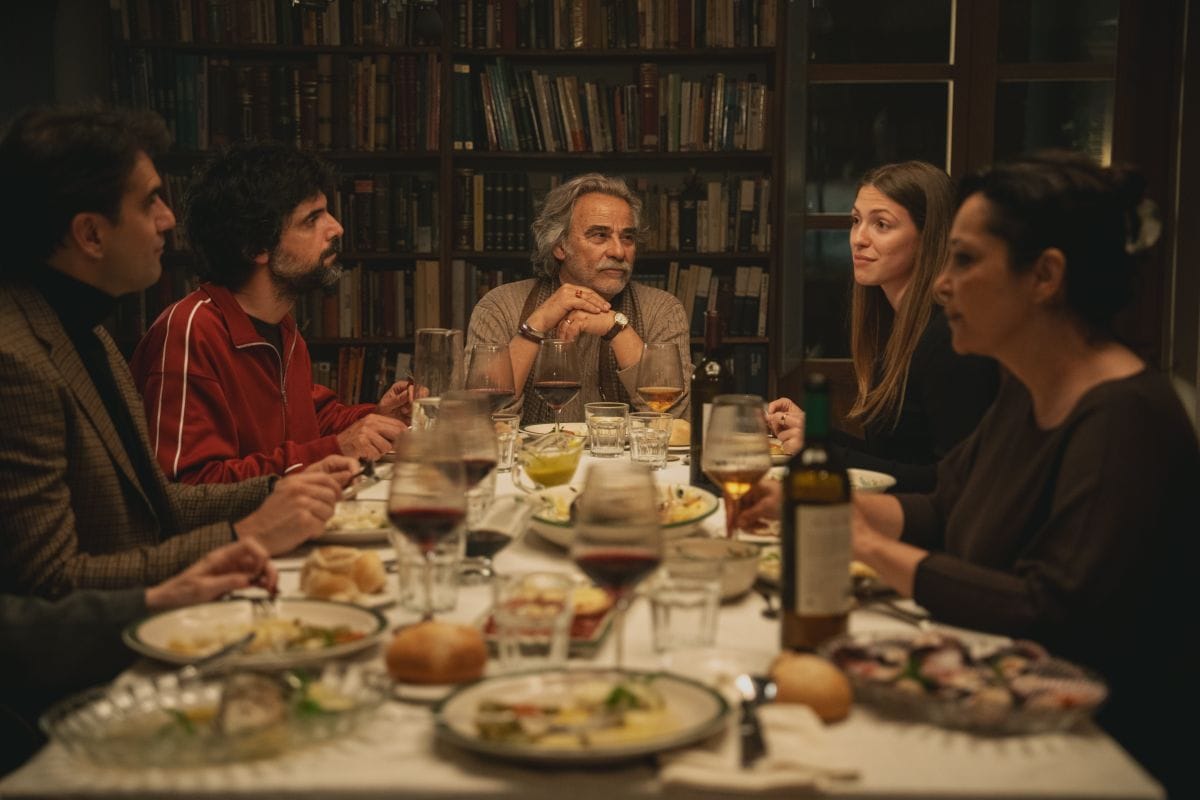
„Още пет минути“ по сценарий на прочутия комик Берто Ромеро, който изпълнява и една от централните роли, е от научнофантастичния поджанр „циклично връщане във времето“ (вж. „Денят на мармота“). С тази разлика, че тук прескоците назад са само с по пет минути, всички действащи лица (двама скарани съпрузи, пристигнали във вила за уикенда, и служителят на агенцията, от която я наемат) ги осъзнават и все по-агресивно се опитват да се избавят от този „затвор от време“…
„Лошият баща“ – също комедия, също във вила – се придържа към реалността, но я обогатява с ексцентричност и пъстри отровни стрели между неспирно спорещите герои: четири отдавна пораснали деца на известен писател на прага на смъртта („Едуард Фернандес е лъв!“, съм си записала в тъмното), няколко съпрузи и съпруги от същия кръг, бохемите от антуража на бащата…
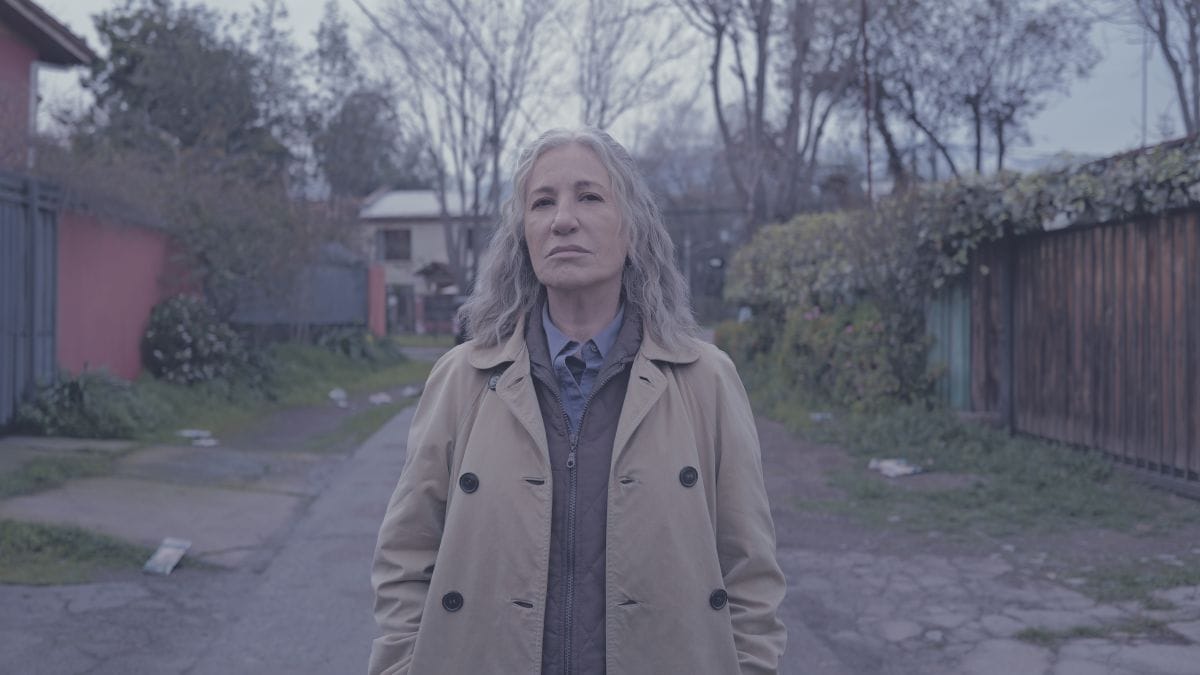
„Тъжните ми мъртъвци“ на чилиеца Пабло Лараѝн по разкази на аржентинската писателка Мариана Енрикес беше от най-чаканите на фестивала. Минисериалът на ужасите (4 епизода по 45 минути за „Нетфликс“, прожектирани в Сан Себастиан в трудносмилаема тричасова форма) смесва остро социално и свръхестествено и е колкото интригуващ, толкова и отблъскващ в хрумванията си. От дете 70-годишната Ема чува и вижда мъртвите, не се плаши от тях, утешава ги, та около нея е постоянен писък и гмеж от неотпътували души, търсещи внимание. Това, заснето в болнавия колорит на Рой Андершон и пропито с делничното насилие на буеносайреските панелни квартали, е донякъде туширано от чувството за хумор на Ема и от чудните актьорски изпълнения, но решително не е за всеки вкус.
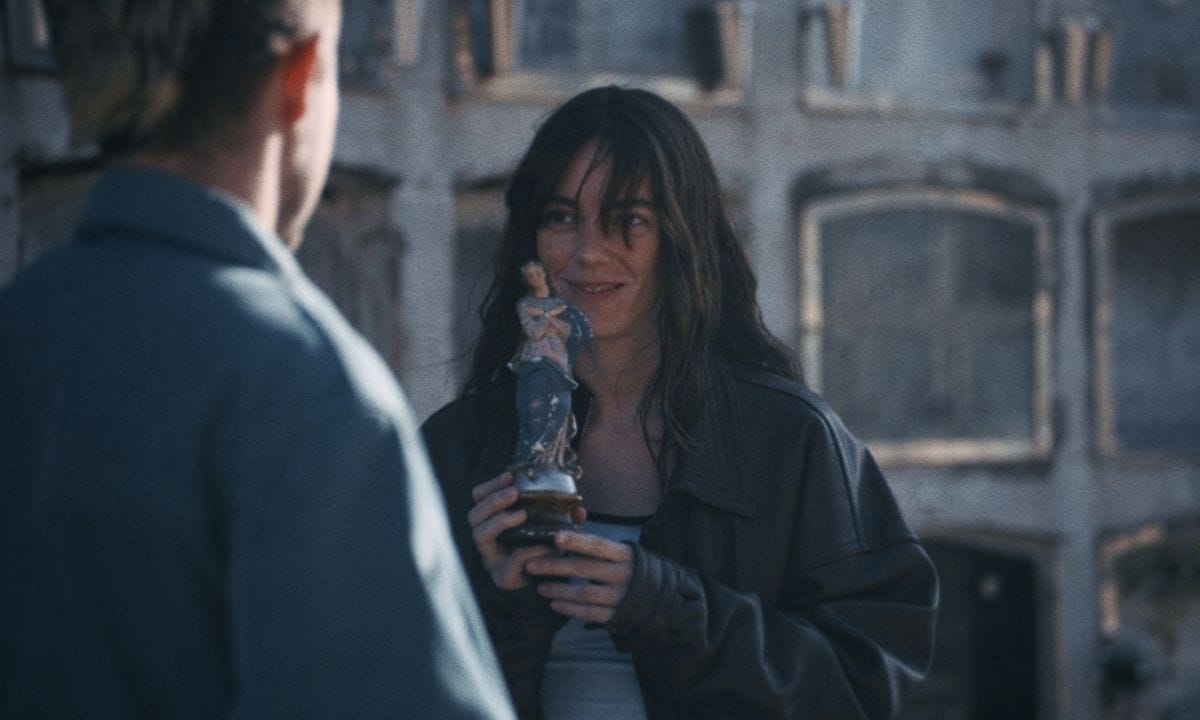
Лали Еспо̀сито в „Глаксо“ на Бенхамин Наищат / кадър от „Граница“ на А Бяо (награда на журито) / кадър с Вики Луенго от „Светци“ на Микел Гореа
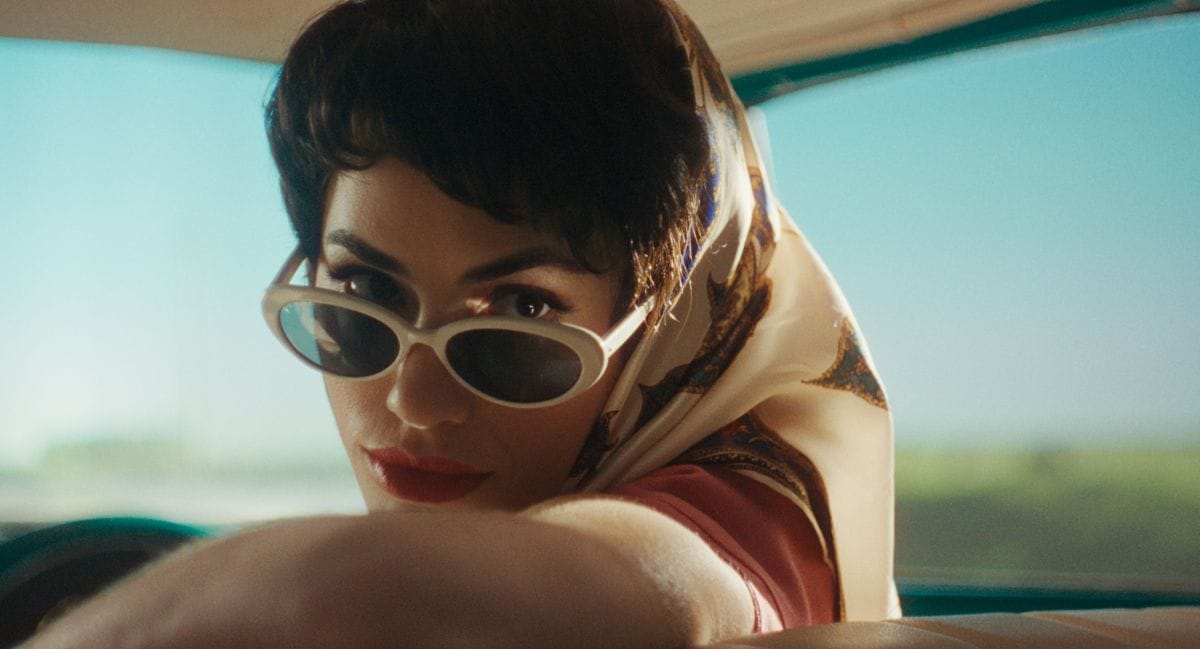
Пак в Аржентина, но в совалка между 50-те до 80-те години, се развива „Глаксо“ на Бенхамин Наищат – романова адаптация за приятелство и предателство на фона на две военни диктатури. Филмът е с твърде много персонажи (и разказвачи), които нямаме време да доопознаем, и макар да е направен с голяма вещина и да държи интереса до края, не пуска корен в ума и сърцето. „Светци“ на Микел Гуреа е друга история от конкурса, която се гледа с любопитство и голяма доза наслада (всеотдайната Вики Луенго в главната роля на хулиганка от периферията; гледките от нощните обири на църкви, в които се замесва героинята ѝ; джазовият саундтрак!), но също не смогва да се досвърже със зрителя – ритъмът и пренавитият патос не успяват да вкарат хармония в хаотичната тъкан и по-скоро отчуждават.
Само няколко филма от състезателната програма тази година бяха откровено разочарование. Но дори и сред тях два бяха способни да не изгубят симпатиите на публиката до финала: „Духове“ на Фатих Акин (дълго черно-бяло упражнение по кичозна сантименталност, в която двама красиви млади актьори разиграват съдбовно предопределена любов между живо момче и мъртво момиче) и „Клетниците“ на Фред Кавайе (превърнал романа на Юго в тричасов костюмиран екшън с гърмяща холивудска музика от ада… и все пак – какви вълнуващи Фантин, Епонин и Жавер!).
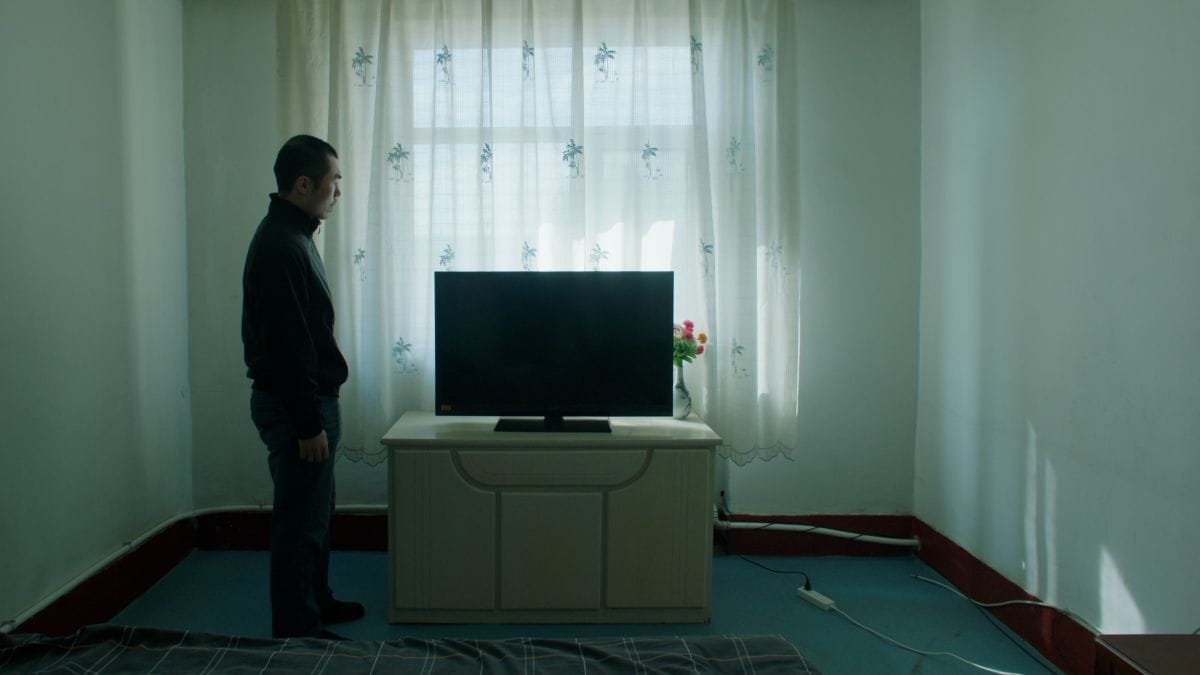
Журито на Айра Сакс направи необяснимо салтомортале в логиката си и присъди своята специална награда на най-слабия филм в тазгодишната сансебастианска подборка – „Граница“, мъчителен дебют на А Бяо. Неми хора с каменни лица, сивкави околности, убоги интериори, монголска проститутка, китайски миньори, сексуални сцени, поднесени патологоанатомично, невидими мотиви, чувства, цели…
Но за да не завършваме на тази необяснима нота, ще се върна към „Благодатта на земята“ и финалната му реплика – не примирена констатация, както може да прозвучи, а обещание за бъдеще:
Никой не е какъвто би трябвало да бъде.
Идната седмица – за разследването „Наза“ (не го пропускайте на 5 октомври от 18:30 часа в Дома на киното – единствена прожекция в рамките на „София ДокуМентал“), за „Обувките на баща ми“ на Христо Симеонов, за триумфите на „Черната топка“, за новото от Мартин Макдона и други находки в програмата на „Сан Себастиан“ 2026.
Optimize consumer rebalancing on Amazon MSK with next generation protocol
Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/optimize-consumer-rebalancing-on-amazon-msk-with-next-generation-protocol/
If you run large consumer groups on Apache Kafka and Amazon Managed Streaming for Apache Kafka (Amazon MSK), you’ve likely experienced the pain of slow rebalances: processing stalls across all consumers, “rebalance storms” triggered by routine scaling events, and prolonged recovery times that impact downstream applications. With the classic rebalance protocol, even a single consumer joining or leaving the group forces a global synchronization barrier, pausing every consumer regardless of whether its partition assignments changed.
The KIP-848 consumer protocol, introduced in Apache Kafka 4.0, fundamentally redesigns how consumer group rebalancing works. Also referred to as “the Next Generation Consumer Rebalance Protocol”, KIP-848 shifts coordination logic from the client to the broker-side group coordinator. This supports fully incremental, server-driven rebalancing that significantly improves performance for large consumer groups. You can use the consumer protocol on Amazon MSK on all 4.x Apache Kafka versions on both MSK Standard and Express brokers.
In this post, we explain how the consumer protocol works, how to enable it on Amazon MSK, and how to diagnose and resolve slow rebalancing issues to help improve performance.
The classic protocol compared to the consumer protocol
The classic protocol relied on client-side rebalance logic with a global synchronization barrier. Every rebalance caused all consumers in the group to pause processing simultaneously regardless of whether their partition assignments were changing. This led to “rebalance storms” in large consumer groups where cascading rebalances could take minutes to resolve. The CooperativeStickyAssignor is a client-side partition assignment strategy that supports incremental, cooperative rebalancing. It significantly improves rebalance performance and minimizes disruption to groups during rebalance events. However, it still suffers from bottlenecks as consumer group size and partition count increase. For large workloads, client-side rebalancing behavior can result in longer rebalancing times and require significant client tuning and monitoring during rebalances.
The consumer protocol addresses these limitations by moving all rebalancing logic to the server. The broker handles coordination using a continuous heartbeat mechanism and server-driven reconciliation process. Only affected partitions move during a rebalance, and consumers with unchanged assignments continue processing uninterrupted. This results in faster recovery compared to the classic protocol, and improved scalability as workloads grow.
The following table compares the classic and next generation protocols across key dimensions.
| Aspect | Classic Protocol | Next Generation Protocol (KIP-848) |
| Rebalance logic | Client-side | Fully server-driven |
| Consumer impact | Depends on assignor, all consumers pause, or rebalance is limited by group size | Only affected consumers impacted, scales effectively as groups grow |
| Mechanism | Client-side algorithm and cross-group coordination | Incremental, async reconciliation |
| Commit processing | Paused during rebalance | Able to progress during rebalance |
| Scalability | Complex, fragile at scale | Resilient, broker-driven |
| Rebalance storms | Common in large groups | Eliminated |
Server-side configuration
With the consumer protocol, key parameters are now configured on the server rather than the client:
group.consumer.heartbeat.interval.ms– Controls the consumer heartbeat interval (server-side).group.consumer.session.timeout.ms– Controls the session timeout (server-side).group.consumer.assignors– Specifies available assignors (uniform and range by default).
In Amazon MSK Express brokers, these configurations are read-only and cannot be modified. In Amazon MSK Standard brokers, these configurations are managed with broker configurations. To update these configurations in Amazon MSK Standard brokers, refer to Update the configuration of an Amazon MSK cluster.
When to use the consumer protocol
The consumer protocol provides the most benefit to workloads with the following requirements:
- Large consumer groups: Groups with many consumers and partitions see the most significant improvements because of the elimination of global synchronization barriers.
- High-availability applications: Applications that cannot afford processing interruptions benefit from continuous message processing during rebalances. Financial services, real-time analytics, and fraud detection systems are ideal candidates.
- Frequently rebalancing environments: Automatic scaling deployments, Kubernetes with frequent pod restarts, or continuous integration and continuous delivery (CI/CD) environments experience significantly less disruption.
- Dynamic partition scaling: Workloads that regularly add partitions or topics benefit from the incremental, server-driven approach.
Prerequisites
Before you begin, make sure that you have the following:
- An Amazon MSK cluster running Apache Kafka version 4.0 or later (both MSK Standard and Express brokers are supported).
- A Kafka client library that supports the KIP-848 consumer protocol (see Step 4 for supported versions).
- Basic familiarity with Apache Kafka consumer groups and partition assignment.
- An AWS account with appropriate permissions to manage your MSK cluster.
Enabling the consumer protocol on Amazon MSK
The following steps walk you through verifying your cluster version, configuring your consumer client, removing deprecated configurations, and confirming client library support.
Step 1: Verify cluster version
The consumer protocol requires Apache Kafka 4.0 or later. To use the consumer protocol on Amazon MSK, verify that your cluster is running Apache Kafka version 4.0.x or later. You can verify your cluster’s Apache Kafka version using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs:
If your cluster is running Apache Kafka 4.0.x or later, the consumer protocol is automatically enabled on the server and ready to use. No additional server-side feature flag verification is needed.
Step 2: Configure consumer client
Set group.protocol=consumer in your consumer configuration. The protocol is not enabled by default:
The consumer protocol can be changed in-place for existing consumer groups. When you update the group.protocol, perform a rolling restart of your consumers. The broker-side group coordinator automatically handles the upgrade to the consumer protocol and handles classic protocol requests from old clients alongside the upgraded clients.
Step 3: Remove deprecated client configurations
When the consumer protocol is enabled, the following client-side configurations are no longer supported because they are controlled by the brokers:
heartbeat.interval.ms.session.timeout.ms.partition.assignment.strategy.
Step 4: Verify client library support
Verify that your Kafka client version supports the consumer protocol:
- Java clients: Generally available (GA) in Apache Kafka 4.0+.
- confluent-kafka-python: Version 2.12.0+ (GA support for KIP-848). See the release notes.
- librdkafka-based clients (Go, .NET, C/C++): Based on librdkafka 2.12.0+.
Note: For other Kafka client libraries, verify your client library’s documentation for group.protocol=consumer support before enabling the next generation protocol. If your client doesn’t support KIP-848, it will continue to use the classic protocol.
Diagnosing slow consumer group rebalancing with the consumer protocol
Even after enabling the consumer protocol, you may encounter situations where consumer group rebalancing takes longer than expected. The following sections help you diagnose and resolve these issues.
Common symptoms
- Consumer group rebalancing takes longer than expected despite setting
group.protocol=consumer. - Consumers pause processing during rebalances.
- Broker logs show “member session expired” or “fenced” messages.
- Frequent rebalances triggered during rolling deployments or pod restarts.
Step 1: Confirm the consumer protocol is active using broker logs
Before troubleshooting performance, verify which protocol your consumers are actually using. Check broker logs in Amazon CloudWatch Logs Insights. The log patterns differ significantly between protocols.
Consumer protocol expected logs:
Key indicators: “consumer protocol”, “epoch” terminology, “target assignment” with server-side assignor, “fenced” for member removal.
Classic protocol expected logs:
Key indicators: “PreparingRebalance” state, “old generation” terminology, “Assignment received from leader”.
If you see classic protocol logs, the consumer protocol is not active. Proceed to Step 2 to troubleshoot why.
Step 2: Troubleshoot why the consumer protocol is not active
Verify that your client configuration, client library versions, and cluster versions support the consumer protocol, as described in the preceding Step 1 through Step 4.
Step 3: Resolve slow rebalancing when KIP-848 is active
After you verify the consumer protocol is active but rebalancing is still slow, investigate the following causes:
A. Consumer session timeout causing premature member removal
With the consumer protocol, session timeout is server-controlled through group.consumer.session.timeout.ms (default: 45 seconds). The diagnostic path depends on whether you are using static group membership. The following table outlines the diagnostic path and recommended actions for each scenario.
| Scenario | Symptom | Root cause | Recommended action |
With static group membership (group.instance.id configured) |
Slow rebalancing when a static member terminates without calling consumer.close() |
The coordinator waits for the full session timeout before reassigning partitions. This is the most common cause of slow rebalancing in containerized environments. | MSK Standard: Implement graceful shutdown to trigger an immediate leave-group request, or increase the session timeout: group.consumer.session.timeout.ms=60000 (default is 45000). MSK Express: This configuration is not editable in Amazon MSK Express clusters. For Amazon MSK Express, optimize your client’s cold starts to allow members to restart within the 45 second consumer session timeout. |
| Without static group membership | Session timeouts expiring during normal operations | Your consumer is freezing or becoming unresponsive, which prevents heartbeats from reaching the coordinator. |
Investigate long-running message processing, garbage collection pauses, network connectivity issues, or resource exhaustion on the consumer host. Look for this in broker logs: [GroupCoordinator id=X] [GroupId <group-id>] Member <member-id> has timed out |
B. Missing graceful shutdown handling
When consumers terminate without calling consumer.close(), the coordinator waits for the full session timeout before removing the member. This is the most common cause of slow rebalancing in containerized environments.
Resolution: Implement proper SIGTERM handling to trigger an immediate leave-group:
For Kubernetes, verify that terminationGracePeriodSeconds allows time for consumer.close() to complete:
C. Frequent rebalances from unstable consumers
If consumers repeatedly join and leave (out-of-memory (OOM) kills, CrashLoopBackOff, or short-lived tasks), each event triggers a new rebalance epoch.
Resolution: Use static membership by assigning a unique group.instance.id:
With static membership:
- Short restarts within the session timeout don’t trigger rebalances.
- The consumer rejoins with the same partition assignment.
- Scaling up (adding new consumers) still works. New
group.instance.idvalues trigger assignment of unassigned partitions only.
Monitoring and validation
After applying changes, confirm the improvement:
- Check broker logs: Confirm that “member session expired” messages no longer appear during normal operations or deployments.
- Monitor consumer lag: Use the
SumOffsetLagandEstimatedMaxTimeLagAmazon CloudWatch metrics to verify that lag returns to zero quickly after a rebalance. - Describe consumer group: Use
kafka-consumer-groups.sh --describeto verify that all members are active and stable.
Conclusion
After implementing the consumer protocol, you should observe the following behavior for consumer group rebalances:
- Consistently faster rebalance times compared to the classic protocol.
- Fewer session timeout-related rebalances.
- More stable consumer group membership.
- Smooth scaling operations without disrupting existing consumers.
- Fewer unnecessary rebalances during consumer restarts when using static membership.
- Clean consumer departures without waiting for timeout expiration when using graceful shutdown.
To get started, try the consumer protocol in your non-production workloads and observe the rebalance improvements as you scale your workload up and down.
To learn more about Amazon MSK and the consumer rebalance protocol, see the following resources:
- Amazon Managed Streaming for Apache Kafka (Amazon MSK)
- Amazon MSK Developer Guide
- Consumer Rebalance Protocol – Apache Kafka documentation
- Troubleshoot continuous rebalancing of your Amazon MSK consumer group
About the authors
Cheryl Strauss Einhorn | The Human Edge: Smarter Decisions in the Age of AI | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=XIYkIWRXAtA
Accelerating airline retailing innovation: how Datalex modernized with AWS Experience-Based Acceleration and agentic AI
Post Syndicated from Kanniah Vagathupatti Jaikumar original https://aws.amazon.com/blogs/architecture/accelerating-airline-retailing-innovation-how-datalex-modernized-with-aws-experience-based-acceleration-and-agentic-ai/
Datalex, a leader in airline ecommerce solutions, set out to answer a question facing every established product-based business: how do you build for where your industry is going, not only where it is today? For more than two decades, Datalex has powered digital retailing for many of the world’s leading airlines, capability built up over years and encoded in a substantial, mission-critical system that runs shopping, pricing, and booking at scale. That depth is a considerable asset, and it is also what makes evolution demanding. The airline industry is moving decisively toward Modern Airline Retailing, an offers-and-orders model with richer integrations and AI-native experiences, and Datalex set out to build the system for that future while carrying forward the proven retail logic its customers rely on every day. The system’s foundations had served that mission reliably for years. The goal now was to modernize the runtime and delivery model so the team could ship the next generation of retailing capability faster, without disrupting the airline operations running on it today. Datalex framed a considered roadmap, Project Phoenix, to get there, and the open question was how much of that journey could be accelerated.
The company’s CTO, Brian Lewis, sponsored the modernization effort and brought together teams across engineering, product, and operations. As Brian Lewis put it, “This is Datalex’s most important project.” The system’s richness was precisely what made the task substantial: years of sophisticated, tightly integrated retail logic that airlines depend on around the clock, built on a mature Java and EJB2 architecture. The team’s central question was never whether the system had value to carry forward, it clearly did, but how to evolve a system of this depth incrementally, at speed and without disruption to airline customers’ operations.
In December 2025, Datalex partnered with AWS for a three-day Experience-Based Acceleration (EBA) workshop. The pace surprised even the system’s own engineers, a measure of how much sophisticated logic they knew sat beneath the surface. As Eric Pitkeathly, Tech Lead, put it: “I did not believe going into the EBA that a migration from EJB/Java 8 to Spring/Java 21 was possible in 3 days! But it was.” This breakthrough did not happen by chance. Following a Modernization Assessment (MODA), the AWS team identified that most of the technological challenges could be accelerated through comprehensive support and the strategic use of agentic AI tools like Kiro and AWS Transform Custom.
This post shares how Datalex used the AWS Experience-Based Acceleration (EBA) methodology to prove modernization feasibility, establish repeatable migration patterns, and integrate generative AI capabilities, all while maintaining their commitment to serving airline customers without disruption.
Solution overview
The AWS Experience-Based Acceleration workshop brought together 16 Datalex engineers with 6 AWS specialists for an intensive three-day engagement at the AWS Dublin offices. Rather than attempting to modernize the entire system at once, the teams focused on proving feasibility through four parallel workstreams, each tackling an important aspect of the modernization journey.
- Stream 1: Microservice prototyping extracted a slice of the Reservation component from the existing n-tier architecture and refactored it into a modern Spring Boot microservice running on Java 21. This workstream proved that migration was technically feasible and established reusable patterns for the remaining code base. The Modernization Assessment revealed a decisive insight: by building a compatible runtime environment, the team could run the system’s existing code on modern technologies with minimal modifications. This was clear evidence that Datalex’s foundations were fundamentally sound and could serve as the stepping stone to the modern system rather than something to be rebuilt from scratch. The remaining code changes were then automated through AI-powered coding assistants like Amazon Q Developer and Kiro, accelerating the transformation.
- Stream 2: DevSecOps pipeline built an end-to-end continuous integration and continuous delivery (CI/CD) pipeline using AWS services including Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Container Registry (Amazon ECR), and AWS Security Hub. The pipeline embedded security scanning at every stage, from code commit through container deployment. This implemented a shift-left security approach that validates infrastructure as code before deployment.
- Stream 3: QA and observability added proactive, real-time monitoring across the system. The team implemented comprehensive observability using Amazon CloudWatch Container Insights, CloudWatch Logs, and Datadog for application performance monitoring. Using the Strangler Fig pattern, the AWS team advised implementing a gateway that could route requests to either the existing REST API or the modernized API through a simple parameter change. This architectural approach supported rapid non-regression testing and real-time validation of the modernization strategy, all within the three-day timeframe. The QA team also created custom dashboards that provide real-time visibility into system health and performance metrics.
- Stream 4: Agentic AI proof of concept demonstrated how generative AI could enhance the system. Using Amazon Bedrock AgentCore, the team built an AI-powered natural language interface for booking retrieval integrated with the existing REST API. The multi-agent orchestration system included specialized agents for authentication, data retrieval, and reporting, all secured through Amazon Cognito and integrated with Kong API Gateway.
The target architecture uses Amazon ECS for container orchestration, with Kong API Gateway providing protocol translation between REST and SOAP while supporting dynamic routing between existing and modernized services. With this approach, Datalex can modernize incrementally without disrupting existing airline operations.
Architecture overview
Modernizing an airline retail system requires integrating new capabilities while maintaining existing operations. Datalex’s architecture shows how to layer generative AI agents, modern microservices, and enhanced observability onto an established, proven system without disrupting customer-facing services. The architecture uses a business service proxy to route traffic between existing and modernized components while maintaining backward compatibility.
Datalex structured their modernization around the following components:
- Demo application: Angular-based frontend demonstrating the modernized user experience.
- Agent orchestrator: Amazon Bedrock coordinates multiple specialized agents for different workflows.
- Business service proxy: Routes requests between existing n-tier architecture and new microservices.
- Modernized services: Spring Boot microservices (SOAP connector and core services) replacing EJB components.
- Current n-tier architecture: Existing services continue operating while being incrementally replaced.
- Event-driven messaging: Apache Kafka enables asynchronous communication between components.
- Observability stack: Amazon CloudWatch, Amazon Managed Grafana, and AWS X-Ray provide monitoring across the layers.
- Security infrastructure: AWS Secrets Manager and AWS Identity and Access Management (IAM) handle authentication and authorization.
Datalex’s AWS cloud environment serves as the foundation, with the business service proxy acting as the request traffic controller. The proxy routes incoming requests to either the existing n-tier system or the new Spring Boot microservices based on migration status. This approach lets Datalex move services incrementally without requiring a big-bang cutover.
The agent orchestrator integrates with Amazon Bedrock AgentCore to manage three specialized agents: authentication, data retrieval, and reporting. These agents handle specific workflows, calling into both existing and modernized services through the API Gateway and business service proxy. An event-driven architecture using Kafka decouples components and enables real-time data processing.
The architecture confirms that Datalex can modernize individual services independently while maintaining system stability. Existing components remain fully operational until their replacements are tested and ready for production traffic.
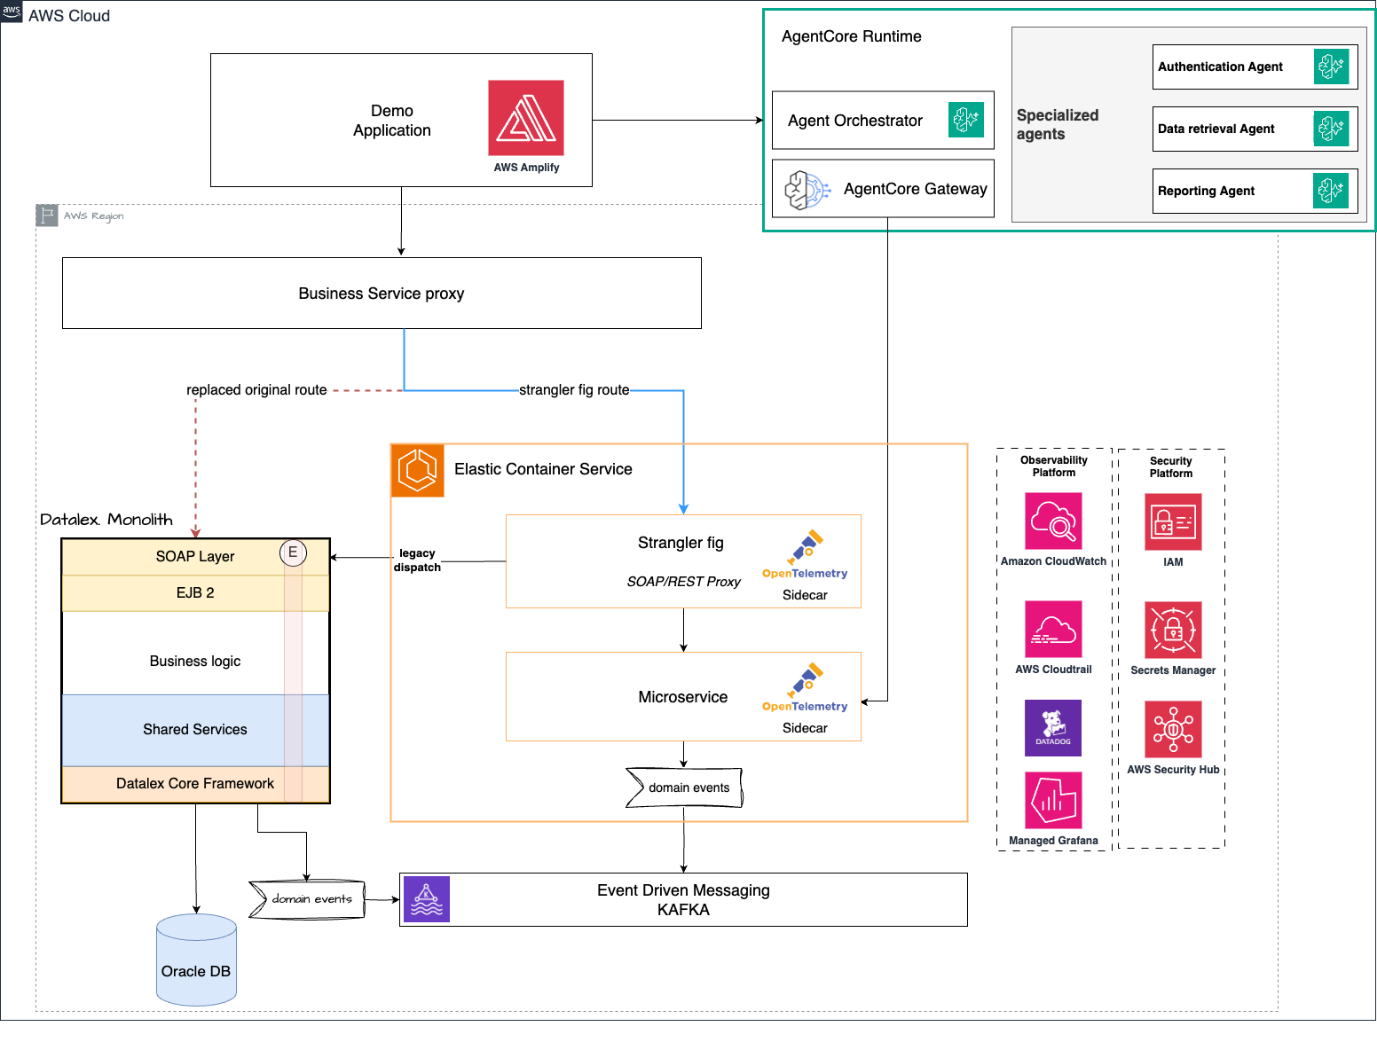
Figure 1: Datalex target architecture with the business service proxy routing between existing and modernized services
The high-level workflow is summarized as follows:
- Route traffic intelligently: Business service proxy directs requests to existing or modernized services based on component status.
- Deploy modernized microservices: Spring Boot services run alongside the existing n-tier architecture in AWS.
- Integrate agent orchestration: Amazon Bedrock manages specialized agents that call both old and new services.
- Enable event-driven patterns: Kafka handles asynchronous messaging between decoupled components.
- Implement comprehensive monitoring: CloudWatch, Grafana, and X-Ray track performance across components.
- Manage secrets centrally: AWS Secrets Manager handles credentials for both existing and modern services.
- Support multiple deployment sources: CI/CD pipelines from GitHub, ECR, and Terraform provision infrastructure.
- Maintain backward compatibility: API Gateway preserves existing interfaces while routing to new implementations.
- Validate incrementally: Each migrated service is tested before the next migration begins.
Technical implementation
Modernizing the system
The prototyping workstream tackled one of the most daunting aspects of the modernization: extracting business logic from a tightly coupled code base. The team selected the Reservation component as their proof of concept because it represented typical complexity found throughout the code base.
The migration involved several technical transformations:
Runtime modernization: Moving from Java 8 to Java 21 brought immediate benefits. Virtual threading capabilities improved concurrent processing, while optimized garbage collection reduced the memory footprint. The team measured a 35% reduction in memory usage compared to the previous JBOSS deployment.
Framework transition: Replacing EJB2 with Spring Boot streamlined the architecture and improved developer productivity. Spring’s extensive testing support improved feature test coverage, while the framework’s modular design allowed for smaller, locally testable service components.
Containerization: Packaging the microservice as a Docker container supported deployment flexibility. The team configured Amazon ECS Fargate to handle container orchestration, avoiding the operational overhead of managing Amazon Elastic Compute Cloud (Amazon EC2) instances running JBOSS.
The migration pattern established during the workshop provides a repeatable approach for the remaining services. Teams can now identify bounded contexts within the system, extract business logic with dependency analysis, refactor to Spring framework patterns, containerize with security hardening, and deploy through an automated pipeline, all while running in parallel with the existing system during transition.
Building production-grade CI/CD
The DevSecOps workstream transformed deployment from a manual, hours-long process into an automated pipeline that completes in under 10 minutes. The pipeline architecture integrates security at every stage:
Build stage: Code commits trigger automated builds using AWS CodeBuild. The build process includes dependency scanning and static code analysis, catching security vulnerabilities before they reach production.
Container security: Images pushed to Amazon ECR undergo automated security scanning. The pipeline validates that the images meet security standards before deployment, with findings aggregated in AWS Security Hub.
Infrastructure validation: Terraform modules defining infrastructure undergo security scanning to verify compliance with organizational policies. This infrastructure-as-code approach provides consistency across environments while maintaining security guardrails.
Deployment automation: The pipeline supports multiple deployment strategies including blue/green deployments for zero-downtime releases, canary deployments for gradual rollout validation, and rolling updates for incremental changes. Native rollback capabilities in Amazon ECS support rapid recovery without operator intervention, improving mean time to recovery.
Implementing comprehensive observability
The observability workstream extended the system with real-time insight into system behavior. The team implemented a multi-layered monitoring approach:
Infrastructure monitoring: Amazon CloudWatch Container Insights provides visibility into container-level metrics including CPU, memory, network, and disk utilization. CloudWatch Logs aggregates logs from the containers for centralized troubleshooting.
Application performance monitoring: Datadog integration provides distributed tracing across microservices, so teams can track requests as they flow through the system. Custom business metrics dashboards surface key performance indicators relevant to airline retail operations.
Proactive monitoring: CloudWatch Synthetics runs automated tests against critical endpoints, alerting teams to issues before customers experience them. This proactive monitoring reduces mean time to detection and resolution.
The observability system also includes an artificial booking generator that streamlines testing for engineering teams, so they can validate performance without requiring production-like data.
Integrating agentic AI
The AI workstream demonstrated how generative AI capabilities could layer onto the modernized architecture without requiring complete system rewrites. The implementation uses Amazon Bedrock AgentCore to orchestrate multiple specialized agents:
Agent architecture: An orchestrator coordinates three specialized agents: an authentication agent for identity verification, a data retrieval agent for accessing business information, and a reporting agent for generating insights. Each agent communicates with backend services through Amazon Bedrock AgentCore Gateway, which translates between the agent’s natural language interface and the system’s REST APIs.
Security implementation: Amazon Cognito provides user authentication and authorization, so airline customers can own agent configuration while maintaining security boundaries. The Model Context Protocol (MCP) Gateway acts as an intermediary between AI agents and REST APIs to support secure communication.
Use case validation: The team built a conversational interface for booking retrieval, so users can query reservation data using natural language. The agent translates conversational queries into API calls, retrieves data from existing Datalex REST APIs, and presents results in a user-friendly format.
This proof of concept validated the technical feasibility of AI integration and established patterns for future AI-enabled features. The architecture provides a foundation for intelligent automation and conversational interfaces that could differentiate Datalex’s product offerings in the airline retail landscape.
Architecture considerations
The target architecture balances modernization goals with operational realities. Amazon Bedrock AgentCore Gateway serves as an important integration layer, supporting gradual migration by routing traffic between existing and modernized services based on configurable rules. With this strangler fig pattern, Datalex can modernize incrementally while maintaining system continuity.
Multi-AZ deployment across Amazon ECS provides high availability, while auto scaling based on CPU and memory metrics makes sure the system can handle traffic variations without manual intervention. The containerized architecture reduces hosting costs through more efficient resource utilization compared to the previous Amazon EC2-based deployment.
Benefits and results
The three-day Experience-Based Acceleration (EBA) delivered outcomes that exceeded expectations. The workshop achieved a 4.9 out of 5.0 customer satisfaction score, with 98% of participants rating their experience as “extremely satisfied.”
Accelerated feasibility proof: What Datalex estimated would take weeks or months to validate independently was accomplished in three days. As the Tech Refresh Dev Manager noted, the AWS team provided a “force multiplier” effect, bringing specialized expertise across modernization, DevOps, and AI/ML domains.
Established migration patterns: The workshop created reusable patterns for migrating the remaining 4 million lines of code. Teams now have documented approaches for extracting services from the n-tier architecture, building secure CI/CD pipelines, implementing observability, and integrating AI capabilities.
Measurable performance improvements: The modernized architecture delivers tangible benefits including a 35% reduction in memory footprint, deployment time reduced from hours to under 10 minutes, 60% faster startup time with Java 21 optimizations, and automated scaling without manual intervention.
Competitive advantage: The modernization positions Datalex to meet growing customer demand for a modern, extensible system. The proven migration path and AI integration capabilities provide competitive differentiation in the airline retail technology landscape.
Cost optimization: Lower hosting costs result from the smaller memory footprint of Spring services compared to existing JBOSS instances. Reduced operational overhead through automation and removal of manual scaling further decreases the total cost of ownership.
Developer productivity: As CTO Brian Lewis observed, “Things that would have taken weeks have been completed in a day.” The modern tooling and frameworks improve the developer experience, while the microservices architecture supports parallel team development and faster iteration cycles.
Looking ahead
Datalex plans to build on the Experience-Based Acceleration (EBA) outcomes through a phased approach. The immediate focus involves maturing the Spring framework to run in parallel with existing JBOSS infrastructure, so teams can gain operational experience before migrating production services.
The company will identify the first production candidate service for migration using the established patterns. The team will implement comprehensive health checks across microservices to support production readiness. They will also quantify cost savings from containerization to provide concrete data for sales teams and executive decision-making.
The AI agent proof of concept opens new product opportunities. Datalex’s product management team will evaluate whether to offer AI-enabled features as product add-ons for airline customers. The conversational interface could improve customer self-service capabilities and reduce operational overhead through intelligent automation.
A follow-up workshop will maintain momentum and address additional modernization challenges. The ongoing partnership with AWS provides access to expertise and best practices as Datalex continues the transformation journey.
Business outcome
The Datalex board approved a significant investment for their technology modernization work, and their prototype tiger team expanded into a fully working Agile team. The Experience-Based Acceleration (EBA) engagement yielded a significant budget for the re-systeming scope of work, with executive-facing KPIs for each quarter mapped against their internal deliverables.
How the Experience-Based Acceleration approach made the difference
The EBA shortened discovery. Datalex estimated 8–12 weeks to validate whether the Reservation component could be extracted without breaking dependencies. With AWS specialists working alongside their engineers, the team had a working response by the end of day one.
It removed cross-cutting blockers. The DevSecOps pipeline required expertise across container scanning, infrastructure validation, and deployment patterns spanning multiple AWS services. The AWS team brought that knowledge into the room, saving weeks of trial and error.
It created evidence for investment decisions. After three days, the team had working code and measurable results they could present to the board. These were proof points that would otherwise have taken three to four months of part-time effort.
Conclusion
Datalex migrated their core services from EJB/Java 8 to Spring Boot/Java 21 in three days during the EBA workshop. The migration established patterns the team now uses across their system, reducing what would have been months of uncertainty into a repeatable process.
The workshop addressed a specific problem: Datalex needed to know if modernization was practical for their code base. By working through one service end-to-end, the team got their response. They also got working code that handles authentication, implements observability, and can run generative AI features, all without rewriting the entire system.
Three lessons from this engagement apply to other modernization projects. First, prove it works on one service before planning the full migration. Second, your team needs to be in the room when the migration happens, because documentation alone will not capture the decisions that matter. Third, add security and monitoring during the migration, not after.
Datalex can now respond to market changes faster and ship features their airline customers are asking for. Their CTO calls this their most important project, and the three-day EBA gave them the technical proof they needed to commit.
If you are planning a similar modernization, AWS Professional Services offers EBA workshops that can help validate your approach. Contact your account team to discuss how this model might work for your system.
Learn more
To learn more about AWS Experience-Based Acceleration programs, visit the AWS Professional Services page. For information about modernizing Java applications, see the AWS Modernization Hub.
About the authors
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
Post Syndicated from Michelle Chen original https://blog.cloudflare.com/clef-decision-models/
Over the last few weeks, there has been lots of buzz around decision models such as Typesafe AI’s Jev System One model. While classifier models have been around for some time, Jev introduces a new decision model concept into the world of AI — a model that produces bounded structured outputs cheaply, quickly and consistently that can be added into a workflow when a decision is required. These models are capable enough to work over any set of inputs without constantly retraining the model to incorporate new classification categories. This contrasts with the world of Large Language Models (LLMs), which are largely non-deterministic, but are open-ended enough to reason and generate text and tool calls for agentic workloads.
Today, we’re releasing two Cloudflare-trained decision models, Clef and Clef-flash, hosted on Workers AI. Clef is currently the leader when evaluated against the Jev Decision Index, you can view full results on the live benchmark demo site. These models are smarter, faster, and fully Jev-API compatible, so you can experiment with these hosted models easily. We’re fully open-sourcing these models on Hugging Face under an Apache 2.0 license for you to run locally and experiment with yourselves.
Lastly, we’re excited to debut our new reinforcement learning (RL) product, which allows customers to fine-tune Clef to suit their use cases as well.
What is a decision model?
A decision model makes classifications to help agents decide how to act, based on certain probabilities. For example, you can pass in a customer support message (inputs) and ask if it is urgent and which team should handle it. A decision model will return typed answers with probabilities (outputs), which your code can use to route the ticket, trigger an escalation, or defer to a human. This means that a human does not necessarily need to be in the loop for agentic decisions anymore — agents can programmatically gather context, make decisions, and take actions on tasks, or defer to a human when needed.
Specifically at Cloudflare, we’ve been testing our new Clef model on our Threat Intelligence team to help us classify website domains. By giving a domain to Clef (with Browser Run) it can quickly identify categories that the domain falls under — for example, it might classify a domain with a 95% chance it is a fashion website, 85% ecommerce, <1% phishing, etc. This classification took our Clef model 2.2s to fetch, render, and classify the website. In contrast, our fastest general LLM gpt-oss-120b took 4.7s in the same workflow, and only returned two classifications. As a user, you can imagine how a 2x savings in latency and results can help us improve our threat intelligence workflows and be faster in identifying malicious or legitimate domains. Generalize this to any use case where you need to make quick programmatic decisions, and you unlock powerful agentic workflows that are able to autonomously decide, reason, and execute.
In music theory, a clef is a symbol placed at the beginning of a musical staff that assigns specific pitch names to the lines and spaces. A decision model is analogous to a music clef because it helps define the domain of the context and the subsequent notes (actions) that follow it. We chose Clef as the name of our family of decision models, as it serves similar purposes, and the CF hearkens to Cloudflare.
How is Clef different from other decision models?
Although the market is getting increasingly saturated with decision models, Clef has some unique properties that make us excited to release it to the public. First, it has a vision encoder so it’s able to take in images and classify visual content. This is different from Jev, which only does text classification today. Secondly, our model has a 64k context window (compared to Jev’s 32k), which allows users to squeeze more input state for the model to classify against.
Third, our model is accurate and powerful, scoring competitively against other decision models on the market across various quality benchmarks. We shortlisted some evaluations below that are important for decision-making as defined by the Jev Decision Index and scored some of the more popular models on the market for it. Check out the table below for benchmarks, or view the scores on our live decision index demo site:
|
Benchmark |
DiffusionGemma Jev |
|||||
|
BFCL · case exact |
98.47 |
98.76 |
95.75 |
96.52 |
94.51 |
38.13 |
|
ToolRet · nDCG@10 |
69.19 |
66.43 |
65.28 |
61.21 |
64.26 |
12.69 |
|
API-Bank · accuracy |
91.93 |
93.11 |
88.19 |
83.66 |
56.30 |
11.41 |
|
Home appliances · case exact |
82.95 |
97.73 |
52.27 |
42.05 |
25.00 |
0.00 |
|
When2Call · accuracy |
72.37 |
65.58 |
80.97 |
75.44 |
49.62 |
11.94 |
|
BANKING77 · macro-F1 |
94.20 |
90.93 |
79.74 |
74.28 |
84.83 |
14.29 |
|
CLINC150+OOS · macro-F1 |
97.43 |
66.77 |
89.27 |
83.49 |
79.03 |
3.19 |
|
BRIGHT · nDCG@10 |
45.91 |
39.26 |
47.52 |
42.94 |
38.53 |
19.90 |
|
Amazon ESCI · macro-F1 |
57.48 |
57.39 |
55.21 |
53.37 |
49.22 |
24.40 |
|
PhishNChips · accuracy |
79.60 |
75.05 |
62.55 |
85.35 |
50.75 |
50.15 |
We also ran benchmarks across Typesafe’s own eval suite and our Clef models fared well, beating Jev in 3 out of 4 areas. Notably, our Clef-flash performs exceptionally well, given how much faster it is.
|
Workflow |
|||
|
Invoice processing |
64.7 |
57.1 |
61.8 |
|
Customer service |
76.3 |
77 |
76.0 |
|
Security incidents |
62.9 |
61.7 |
61.7 |
|
Agent trace observability |
68.5 |
69.8 |
71.6 |
Across the 43 eval benchmarks that we ran, our Clef models beat the decision models on latency (except for Laya which is very fast but trades off quality in the benchmarks above):
|
Benchmark |
DiffusionGemma Jev |
|||||
|
Median latency · ms |
209.3 |
38.8 |
524.1 |
84.4 |
51.4 |
5.8 |
|
p95 latency · ms |
238.6 |
122.4 |
536.0 |
211.2 |
187.9 |
222.5 |
On top of the latency benefits from the model itself, our Clef models are hosted on Workers AI. Because they are hosted on Cloudflare’s infrastructure, we’re able to take advantage of our GPUs at the edge, leading to low network latency and faster decisions. This means that you could put Clef into the hot path for agents to make decisions and combine that with one of our LLMs on Workers AI to take action.
Clef also produces strictly typed outputs similar to Jev and is fully API-compatible, so you can make the swap extremely easily. The larger Clef model is your more powerful precision model, while the Clef-Flash model is great for latency-critical decisions. The models are enterprise-ready with our guarantee that we don’t read, store, or train on your requests or responses (unless you want to use our fine-tuning product, which we go into below). You can get started with the Clef models today, starting with our developer documentation or play around with the open-source model on the Hugging Face repo.
If you’d like help tuning Clef for a specific workload, we are also offering fine-tuning services — first as a hands-on partner with our forward-deployed engineer (FDE) team, and then later as a self-serve fine-tuning platform for customers to train and redeploy the model onto Cloudflare.
How we trained Clef
In the same week that Jev came out, we posted about some experiments we had with our own homegrown decision model. Our demo goes into how we adapted the DiffusionGemma model to output deterministic probabilities by exposing the logprobs that are generated by a large language model. Our initial approach built upon independent research by Matt Mastracci, who has been active in the machine learning (ML) community with sharing new ideas and pull requests to vLLM inference engine to make DiffusionGemma support stronger.
Clef builds upon this concept, but uses a different base model as the backbone. We currently use Qwen as the base model and post-trained it to suit decision model use cases. During inference, Clef uses Qwen for a prefill-only pass, then scores the valid schema choices in parallel. The decision step is non-autoregressive, so there’s no intermediate text to generate token by token, making Clef significantly faster than autoregressive LLMs. Rather than generating intermediate text to produce structured answers, Clef and Clef-flash derive schema choices directly from internal backbone representations. This approach relies on a specialized two-stage attention routing process: every valid choice extracts context relevant to the prompt, allowing individual field parameters to cross-attend with other fields and back to the original payload prior to scoring. By leveraging a lexical prior, the model preserves semantic intent across options. Ultimately, the architecture unites option-specific evidence routing, joint cross-field attention, and schema-bound scoring.
By freezing Qwen3.8-27B for Clef and Qwen3.5-9B for Clef-flash, we jointly optimized the routing head alongside rank-256 low-rank adapters. Our post-training utilizes label-smoothed cross-entropy for valid schema outputs paired with a Brier loss to refine probability calibration. This training leverages our own internal synthetic datasets permutating field orders, prompts, and schema structures. We also developed Reinforcement Learning for Calibrated Decisions (RLCD) to serve as a secondary optimization target, granting partial credit to adjacent ordinal choices, rewarding fully precise record outputs, and applying a reference penalty to prevent distribution shift, giving us better accuracy and generalization.
This means that we were able to achieve a few novel things with Clef: we improved accuracy of the model in classification, constrained it to output only probabilities instead of text generation, and made it faster than Jev and the base Qwen models.
How fine-tuning can extend the capabilities of Clef
We heard a lot of internal use cases that required fine-tuning our Clef model to be built into our agentic workflows at Cloudflare. For example, internal teams want a classifier model to be able to evaluate Trust & Safety submissions, help us triage Cloudflare Support requests, or even to be built-in to our Bot products to decide if a crawler is a good bot or bad bot.
These use cases are incredibly specific and we have had many years of labelled decisions that we could use to train a specific classifier. When you fine-tune a model, you may give up some general purpose performance in exchange for higher accuracy in a specific domain.. Because Cloudflare has more than 15 years of network data across different domains, we can fine-tune a model to fit these specific use cases which is more accurate and faster than our generic Clef model. We’re working with internal teams already to figure out how we can post-train Clef to create powerful ML models that boost our impact and improve workflows across Cloudflare. These internal teams and use cases are the next remit of our new FDE fine-tuning team and basis for our reinforcement learning (RL) product.
Our new RL service
We are offering a service to help customers fine-tune Clef to suit their workloads with our hands-on FDE team. From that, we’ll learn from our hands-on experiences to build a self-serve platform that customers can use to capture data, fine-tune, and redeploy the model, all on Cloudflare.
This has actually been a long time coming — we’ve been building our AI platform to have the right primitives where we could be building a custom RL product. The interest in Jev shows the need for a fast, small, specific, classifier model, and we chose this to be our niche to start experimenting with RL environments.
To do this, we leverage the primitives that we already have built on our Cloudflare platform:
- Cloudflare AI Gateway – pass all your AI traffic through AI Gateway and automatically create a dataset of requests for your use case
- Cloudflare Workers AI – generate rollouts against the base Clef model
- Cloudflare Containers – RL sandbox for scoring and replaying agent actions
- [NEW] Trainer – update weights of fine-tuned Clef model
- Cloudflare Workers AI + BYO Model – redeploy the fine-tuned model on Workers AI
This combines a few work-in-progress pieces of the AI Platform that we’ve been working on, including AI Gateway that captures your AI traffic so you can leverage your own request/response data, Containers for RL Sandboxes, and Workers AI’s Bring Your Own Model (Cog) work that has been progressing since our acquisition of Replicate.
Try it out today
We’re excited to launch our first Cloudflare-trained ML model from the Workers AI team today. We’re still early here and have a lot more improvements in store, but it is a wonderful first showcase of the hard work we’ve been doing on the AI Platform team. We believe that Clef has the ability to disrupt the way we use agents, which fits naturally into Cloudflare’s mission of being the agent cloud.
If you have specific use cases and are already customers of these products — we’d love to chat with you and be design partners as we experiment in this space.
Try out the Clef models hosted on Workers AI, download the weights on Hugging Face if you’d like to explore for yourself, and reach out if you have fine-tuning use cases you’d like us to help with.
Our ML team has been growing in impact, from model optimizations to model training research. If you’re interested in joining our mission, check out our open roles.
[$] Coping with the onslaught of kernel security bugs
Post Syndicated from corbet original https://lwn.net/Articles/1096908/
By now it is no secret that large language models (LLMs) have made it easy
for people to identify security bugs, and that has resulted in a flood of
bug reports to almost every free-software project, including the kernel.
At the 2026 edition of Kernel
Recipes, Greg Kroah-Hartman took the stage to talk about how the
kernel’s security team is handling this deluge. His core message was
“don’t panic
“.
How Mirelo AI brought sound design to the IDE with MCP and Kiro powers
Post Syndicated from Florian Breton original https://aws.amazon.com/blogs/devops/how-mirelo-ai-brought-sound-design-to-the-ide-with-mcp-and-kiro-powers/
Mirelo AI set out to fix how sound design works in the integrated development environment (IDE). For most developers, sound design has always meant leaving the IDE: opening a browser, digging through stock libraries, and trimming and syncing clips by hand. Sound is the last creative layer most developers reach, and the one they most often get wrong without specialist help. For teams building games, apps, and interactive products, digital audio workstations (DAWs) live outside the development workflow, so most ship with placeholder audio or nothing at all.
Mirelo AI, a Europe-based generative AI lab, builds models that turn a text prompt or a video clip into production-ready sound effects, synced to the picture when video is provided. Feed a video clip to the model and it returns audio matched to the action on screen. Mirelo built a hosted server on the Model Context Protocol (MCP), the open standard that lets AI assistants discover and call external tools. With Mirelo’s hosted MCP server, developers can reach those models from the tools they already use.
In this post, we describe how that MCP server became a power in Kiro, the agentic development environment from AWS. We also cover how Mirelo’s AWS Enterprise Support account team helped bring it to the Kiro powers marketplace. The result: Developers using Kiro can generate sound design from a natural-language prompt without leaving their editor.
Solution overview
With a Kiro power, you get Mirelo’s hosted MCP server bundled with Agent Skills that tell the AI assistant when and how to use it. When a developer’s prompt mentions sound, audio, or effects, Kiro activates the power, connects to Mirelo’s server, and loads its tools into the conversation. The developer describes the sound they want. Kiro calls Mirelo’s models and returns a finished audio file into the project.
The design has three parts:
- Mirelo’s audio models, exposed through their existing HTTP API.
- The hosted MCP server (https://mcp.mirelo.ai/mcp), which wraps that API as callable tools.
- The Kiro power, which bundles the MCP configuration with an Agent Skill and publishes it to the marketplace for one-action install.
The problem: Sound is the last mile of creative development
Visual assets have mature tooling inside IDEs and design systems. Audio does not. A game developer prototyping a level generates textures, writes shaders, and tests physics in the editor. But the moment they need a matching footstep sound, the flow breaks. They open a browser, search a stock library, download candidates, trim them to length, and manually sync timing.
Content creators working with generative video hit the same wall from the other side. AI models now produce visual content in seconds, but each clip ships silent, so adding sound means switching tools, breaking flow, and spending more time on audio than the video itself took to create.
Mirelo’s thesis: Sound generation should live where developers already work, not in a separate application.
From API to agent tool: The Mirelo MCP server
Mirelo already had an API powering their Studio product. The question was how to make those capabilities reachable inside AI-powered development environments without asking developers to write integration code.
MCP answers that. By wrapping their API as an MCP server, Mirelo exposed their full audio generation pipeline to any compatible AI assistant. The Mirelo MCP is hosted and remote: developers add a single URL, authenticate through their browser, and start generating audio from conversation. There’s no local install and no API key to manage.
The server covers the full sound design loop:
- Generate from text: describe a sound effect in natural language and receive a finished audio file.
- Generate from video: pass a video clip and get synced sound effects for every action.
- Extend: lengthen an audio clip that is too short for the scene.
- Inpaint: replace a selected region of a clip while leaving the rest untouched.
A preflight tool estimates credits and runtime before generation runs, which matters when an agent works through a batch of files rather than a single effect.
Comparing direct API access with a Kiro power
Without the power, a developer who wants a sound effect works against the API directly. For anything longer than a short clip, that means the asynchronous path: submit the job, get a job ID back, poll for status, then download the result once it completes. A minimal version looks like this:
This works, but the developer owns every step. They store the API key, choose the sync endpoint for short clips and the async endpoint for longer ones, and call preflight to estimate credits. They also run the poll loop with sensible backoff, handle the failure state, download the result, and retry on transient errors. Each surface, whether a web app, a game editor, or a batch script, reimplements the same glue.
With the power, the developer describes the sound and the agent assembles that same request. Kiro authenticates through browser sign-in and reads the tool schema Mirelo published. It fills in prompt, duration_ms, and output_format from the conversation, runs the preflight tool when the job is large, and waits on the async job when generation runs long. The developer writes:
Generate 45 seconds of heavy rain on a metal roof with distant thunder, as an mp3.
The file is added to the project. The underlying API call is the same. What changes is who assembles and operates it.
The following table compares the two paths:
| Concern | Direct API | Kiro power/MCP tool call |
| Authentication | Store and send Bearer sk-… on every call | Browser sign-in, managed by Kiro |
| Cost check | Call /preflight yourself | Agent calls the preflight tool when the job warrants it |
| Sync compared to async | You choose the endpoint and implement polling | Agent selects based on job size |
| Response handling | Parse result_urls and download | Agent returns the file into the project |
| Reuse across tools | Reimplement the glue per surface | One power, available in any Kiro session |
Why package it as a Kiro power
Mirelo’s MCP server already worked in several AI assistants. With a Kiro power, you get discoverability, so you find the integration while browsing the marketplace, and automatic activation, so there is no URL to paste or configuration to write.
A power bundles an MCP server with Agent Skills, the structured instructions that guide an AI assistant through a specific workflow. The AI assistant learns what tools exist and when to reach for them. Just as important is how a power loads. A traditional MCP setup registers every tool definition upfront. Connecting a handful of servers can burn tens of thousands of tokens, a large share of the context window, before your first prompt. Kiro powers load dynamically instead. Installed powers sit dormant until your conversation mentions relevant keywords, at which point Kiro activates only that power’s tools and skills and deactivates them when you move on. Skills load the same way, on-demand, so the AI assistant pulls in a specific workflow’s instructions only when it’s working on that task. The result is near-zero baseline context cost and a Mirelo integration that surfaces its sound-design tools exactly when they’re needed, without crowding out the rest of your work.
The structure of a power is small. The following layout shows the three files that define it:
The plugin.json manifest declares the keywords that trigger activation. The mcp.json file points to the provider’s hosted server. The skill teaches the agent the difference between generating a one-shot effect and sound-designing an entire sequence.
The path from idea to marketplace
The Kiro powers connection came from Mirelo’s AWS Enterprise Support account team. The team spotted the fit between Mirelo’s MCP server and the powers marketplace. They built a proof-of-concept power to show how the integration would work and connected Mirelo with the submission process. Mirelo then packaged their official hosted server as the published power.
From the first conversation to a live power took about two weeks, most of it marketplace review. The engineering itself fit into a single afternoon. The impact is easiest to see in the developer’s workflow. Finding a single sound effect that matches the video is slow, manual work. That includes searching a stock library, auditioning candidates, trimming, and syncing. With the power, a single prompt returns a usable, synced clip, replacing a lengthy manual workflow with one step.
What developers can do with it
After the Mirelo power is active, sound design becomes part of the conversation. A developer polishing a web app might ask:
Generate a soft, satisfying click for this submit button. Short, no metallic ring.
On a game prototype, the request could be:
Here’s my gameplay clip. Generate footstep and impact sounds that match the character’s movement.
For a video project that needs a longer bed:
Extend this forest ambience to forty-five seconds so it covers the full scene transition.
And to fix a single moment:
The glass-break sound at 0:03 is too harsh. Inpaint that region with something more subtle, like thin crystal.
Each request calls Mirelo’s models and returns audio ready to use, without the developer leaving the editor.
A distribution channel for AI model companies
For Mirelo, the Kiro powers marketplace is a new kind of distribution. API businesses have historically reached developers through documentation sites, SDKs, and marketing. A power puts the capability inside the tool developers already use. Developers reach it by intent rather than by integration work.
The model fits AI services that augment creative workflows. Developers don’t plan to use a sound API the way they plan to use a database. They need sound the moment they realize their project is silent. A power meets them at that point of intent.
Conclusion
In this post, we described how Mirelo AI turned a hosted MCP server into a Kiro power, and how AWS Enterprise Support helped move it into the marketplace. For developers, sound design is now a prompt away inside Kiro. For AI model companies, the same path turns an existing MCP server into a distribution channel that reaches developers at the point of intent.
To get started:
- Install the Mirelo power from the Kiro powers marketplace.
- Try Mirelo and connect the hosted MCP server to your AI assistant.
- Read the Kiro powers creation guide to package your own MCP server.
- Review the Agent Plugins specification to build portable, vendor-neutral plugins.
About the authors
All the Cool Kids Are Birding
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/MBFGL2P8-II
Min Jin Lee’s Underdog Morality
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=CdV3QDPbOIk
Not all explanations are equal: Social Explainable AI and Critical Computational Literacy
Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/not-all-explanations-are-equal-social-explainable-ai-and-critical-computational-literacy/
AI technologies, such as smart speakers or streaming recommendations, are becoming part of everyday life for children and teenagers. It’s therefore increasingly important to help young people understand not just how these systems work, but how to question them.
When AI systems generate outputs such as a recommendation, these outputs are often accompanied by an explanation. In our latest research seminar, Professor Dr. Dan Verständig (Goethe University Frankfurt, Center for Critical Computational Studies) spoke about how explanations are shaped by the people who write them, and only become meaningful when someone else makes sense of them. Dan introduced us to Social Explainable AI (Social XAI) and Critical Computational Literacy (CCL), and asked us to consider not just what an AI system explains, but for whom, why, and who benefits.
Why do we need explanations?
Dan opened with a deceptively simple question: why do we need explanations in the first place? His answer was that explanations provide orientation. They reduce uncertainty, and in doing so, they make our shared social world liveable. Explanations have evolved from Socratic dialogue, to the printed book, to the classroom, to today’s digital interfaces, and now to AI-generated explanations. But explanations have never been neutral conveyors of information. Dan illustrated this with a simple demonstration: he showed the seminar participants an aerial photo of a beach and asked what they noticed.
The aerial photo Dan shared during his seminar. What do you notice about this picture?
Seminar participants pointed to the coastline, the sandy beach, and a tiny figure in the frame. Dan then revealed that the photo was taken by him, using a drone at Montara State Beach in California on a specific afternoon in April 2024. He asked how a climate researcher, a surfer, or an artist might each describe the very same image differently.
This demonstration highlighted that an explanation is always for someone, for some purpose, in some context. That framing carries straight through into how we should think about AI explanations too. An explanation that satisfies a data scientist debugging a model is not the same as one that satisfies a patient asking why an algorithm flagged their scan, or a citizen asking why they were denied a loan. In other words, explanations are never technical.
From delivering explanations to co-constructing them
Drawing on Rohlfing and Lim’s 2026 work, Dan described Social XAI as an approach that puts interaction, rather than output, at the centre of explainability. Dan illustrated this with a simple but effective diagram: an AI explanation starts as a system output, is filtered through a person’s interpretation, and only then becomes meaning through construction. A one-size-fits-all output, however technically accurate, isn’t yet an explanation until someone has made sense of it in their own terms.
To explore this further, Dan’s research group has developed co-construction workshops, bringing people together to interrogate AI explanations collaboratively rather than receive them passively. In these workshops, participants are asked questions such as: “What counts as evidence? What is missing? What are the alternatives? Who benefits from this? Do we agree?”
To answer these questions, participants do not examine an AI model to find out how it generates a decision. Instead, participants scrutinise its outputs in the same way that they would critically evaluate a politician’s promise or a newspaper’s headline.
Dimensions for engaging critically with explanations
Critical Computational Literacy (CCL) is a framework that describes what people need to engage with AI explanations critically. Dan presented CCL as consisting of four interlocking dimensions:
- Attitude — a critical stance and value awareness: approaching computational systems not as neutral tools but as artefacts that embed particular values and assumptions
- Biography — recognising that people’s relationships with technology are shaped by subjectivity, by the varied encounters they’ve had with computational systems, and by the diverse pathways that brought them to this point
- Capacity — the analytical, creative, and ethical skills needed to actually work with and through computational systems, not just talk about them
- Critique — the capacity that ties the other three dimensions together: asking what matters, and why
Taken together, these dimensions push back against a narrow, purely technical notion of ‘AI literacy’ as knowing how a model works. Instead, CCL treats literacy as something biographical and value-laden. Dan explained that individuals bring their own history and stance to any encounter with computational systems, and genuine literacy means being able to interrogate these systems’ explanations rather than simply accept or operate them.
Using these ideas in your classroom
Although Dan’s research took place with adult participants, Social XAI and Critical Computational Literacy are ideas that could also be used in the K-12 classroom. For example, if students interact with AI explanations through smart speakers or streaming recommendations in their everyday lives, this presents an opportunity to teach them how to engage critically with AI outputs. Students might explore why a smart speaker suggested a particular recipe, or investigate the explanation for why a streaming service recommended a particular show.
Explainability is also a key part of our own Experience AI resources. When training a model, students write their own model cards to document who built a model, what training data was used, how accurate the model’s predictions were, and any known limitations. In this activity, explainability is traceable, and students use their analytical skills to create transparent, fair, and accountable model cards.
Social XAI suggests an extension to this activity. Students could ask what matters about the explanation they have written and why this is important. Through this critique, students can consider who will read these model cards and how the cards might be interpreted. In this way, AI explanations become more than a technical output, and become artefacts whose meaning is co-constructed by the author and the reader.
This seminar was part of our ongoing series on teaching about AI in the arts, humanities, and sciences. You can watch the full recording of Dan’s talk, including the Q&A discussion, here:
Join our next seminar
Our research seminar series continues to explore how AI is taught across the curriculum. In our next seminar on Tuesday, 6 October at 19:00–20:30 BST, we welcome Eleni Petraki and Damith Herath (University of Canberra) who will present an engineering and robotics curriculum aimed at equipping future engineers with the diverse skills demanded by a growing workforce. To take part in the seminar, click the button below to register. We hope to see you there.
The schedule of our upcoming seminars is available online. You can catch up on past seminars on the blog and on the previous seminars and recordings page.
The post Not all explanations are equal: Social Explainable AI and Critical Computational Literacy appeared first on Raspberry Pi Foundation.
Rust 1.99.0 released
Post Syndicated from corbet original https://lwn.net/Articles/1098068/
Version
1.99.0 of the Rust language has been released. Changes this time
include support for extern "C" variadic functions, the
establishment of functions for obtaining the size and alignment of raw
pointers, a number of stabilized APIs, and more.
Security updates for Thursday
Post Syndicated from jzb original https://lwn.net/Articles/1098067/
Security updates have been issued by AlmaLinux (corosync, gawk, gdb, nodejs24, and thunderbird), Debian (expat, firefox-esr, libsmpp34, mkvtoolnix, network-manager-l2tp, pgextwlist, python-django, ruby-oj, and tor), Fedora (apptainer, ckermit, ffmpeg, freerdp, librabbitmq, openbao, php, python-cssselect2, python-uv-build, ruff, rust-libcst, rust-libcst_derive, rust-salsa, rust-salsa-macro-rules, rust-salsa-macros, sos, ty, uv, weasyprint, and xdg-dbus-proxy), Mageia (python-pillow), Red Hat (acl, glib2, go-toolset:rhel8, golang, libxml2, mingw-sqlite, nodejs-nodemon, nodejs22, nodejs24, nodejs:22, nodejs:24, sqlite, tesseract, and vim), Slackware (libpng and mozilla-thunderbird), SUSE (alloy, chromedriver, emacs, gdb, gimp, gpsd, jawn, libpoppler-cpp3, libtesseract5, multipath-tools, netty, ntfs-3g_ntfsprogs, pcapplusplus-devel, pi-coding-agent, python-PyYAML, python-tornado, python-tornado6, python311, python313, and wicked2nm), and Ubuntu (designate, gst-plugins-bad1.0, gvfs, imagemagick, kdenlive, mlt, keystone, libauthen-sasl-perl, linux-aws, linux-aws-6.8, linux-nvidia-tegra, linux-nvidia-tegra-igx, linux-oracle-7.0, opensbi, openvpn, and python-django).
One year later: Sovereign AI and the fight for choice
Post Syndicated from Carly Ramsey original https://blog.cloudflare.com/sovereign-ai-choice-one-year-later/
It's Birthday Week, when we traditionally ship presents to the Internet. This year, two of them come from Europe: EuroLLM, which covers all 24 official EU languages, and Apertus, Switzerland's fully open model, trained on more than 1,500 languages. Both were built by public universities and research institutions. Both are coming to Workers AI, and you can request access today.
We're also launching hands-on workshops that help government cyber agencies and critical infrastructure operators build AI defenses that work with any model. The first runs in Singapore in October.
Today's announcements follow from an argument we made a year ago, when questions about AI access and sovereignty were swirling in national capitals. Our answer was choice: the freedom to pick the right tools for the job, and to switch when you need to.
Since then, those conversations have hardened. Attackers have used frontier models to run cyber attacks. Access to some frontier models now depends on where you are. Calls to restrict open models are getting louder. Put it all together and it's easy to conclude that AI sovereignty is zero-sum: every model another country controls is one you can't count on, so the safe move is to build walls.
We think the past year can point the other way. India, Japan and Singapore focused on open-sourced models, and people across Asia-Pacific built tools on them for rural citizens, elderly patients and the nurses who care for them. Our own security team built AI defenses that work with any model, so losing access to one doesn't mean losing your defenses.
Helping build a better Internet has always meant more options, not fewer. That's why we work on open standards that prevent vendor lock-in, why so much of what we build is free to start with, and why our network runs in more than 335 cities across 125+ countries, with GPUs for AI inference in more than 230 of them. We don't think any country should have to depend on one company for its AI. That includes us.
Two European open models on Workers AI
In February, Matthew Prince told the India AI Impact Summit 2026 in New Delhi that decentralized, affordable access to AI is a matter of national resilience. The models from India, Japan and Singapore we'd added a few months earlier were our first proof. The summit series moves to Geneva in June 2027, with a mission of "prosperity and progress for all."
EuroLLM supports 35 languages, including all 24 official EU languages, many of which are underserved by existing open models. It was developed with support from Horizon Europe, the European Research Council and EuroHPC by a consortium that includes Instituto Superior Técnico, the University of Edinburgh, Instituto de Telecomunicações, Université Paris-Saclay, Unbabel, Sorbonne University, Naver Labs and the University of Amsterdam. It was trained on the MareNostrum 5 supercomputer and, according to the consortium, outperforms similar-sized models on EU multilingual benchmarks and machine translation.
You can request access to EuroLLM on Workers AI here.
Apertus (Latin for "open") is Switzerland's first large-scale, fully open, multilingual language model. It was trained on more than 15 trillion tokens across more than 1,500 languages, with 40% of training data in languages other than English. It was developed by ETH Zurich, EPFL and the Swiss National Supercomputing Centre (CSCS) as part of the Swiss AI Initiative: built by public institutions, for the public good. Its architecture, weights, training data and methods are all published. It was designed with Swiss and European rules such as the EU AI Act and GDPR in mind, which means respecting training opt-outs, removing personal data and preventing memorization. It was trained on CSCS's Alps supercomputer (more than 10,000 GH200 GPUs), and its developers report that it significantly outperforms leading closed and open models on rare and regional languages, from Romansh and Swiss German to low-resource languages across Asia and Africa.
You can request access to Apertus on Workers AI here.
What people built last year
Last year's national models didn't sit on a shelf. Since we added them to Workers AI, hundreds of students, startups, small businesses and public servants across Asia-Pacific have built on them, many at buildathons we ran with local partners. Three of them:
- Government forms, no reading required – Form Mitra (India): Benefit forms written in dense English shut out many of the rural, low-literacy and visually impaired citizens they're meant for. Students at the Indian Institute of Technology Delhi built Form Mitra at a buildathon we ran with CyberPeace: a voice-guided assistant that walks people through the form in any of 22 Indian languages, using AI4Bharat's IndicTrans2 model.
- Care in the patient's own dialect – MedBridge (Singapore): Many of the nurses caring for Singapore's elderly patients come from across Southeast Asia and don't speak the local dialects, so critical clinical information can get lost in translation. MedBridge guides patients through health conversations in 14 languages, including Hokkien and Cantonese.
- The right public service, in one tap – Anshin Concierge (Japan): For elderly residents, people with disabilities and anyone less comfortable with digital tools, working out which public service to call in a moment of need can be overwhelming. Built as a hackathon prototype, Anshin Concierge lets people describe the problem in their own words ("my knees hurt", "a strange screen appeared on my phone") and connects them to the right Tokyo Metropolitan Government support desk, by phone or web page, in one tap.
AI defenses that don't depend on one model
Governments want to use AI to defend essential services and national infrastructure. The frontier models that can find vulnerabilities at scale can find them for defenders too. But a defense built on one model is only as dependable as your access to that model, and governments have watched access to critical models get constrained with little warning.
We had the same problem, and in security we are always our own first customer. Over the past year, our Security team, working with teams across the company, set out to build AI defenses that don't depend on any one model. We built a harness: an orchestration layer that coordinates multiple AI models working in parallel to hunt for vulnerabilities, verify findings and prioritize threats. We published what we learned about using frontier and open models together, open-sourced the harness so any organization can run it with the models of its choice, and laid out the layered architecture we use to stop attackers armed with frontier models from finding vulnerabilities in the first place.
Because the harness works with any model, closed or open, losing access to one provider doesn't switch your defenses off. When we walked governments through it, the most common reaction was relief. Then came the practical questions: how to stand it up in their own environments, under their own rules. Briefings quickly turned into requests for hands-on training.
So today we're launching a program of hands-on workshops for government cybersecurity agencies and critical infrastructure operators. Participants build their own AI security harness and layered defenses, and leave knowing how to adapt both to their organization. The modules are plug-and-play, designed to slot into national AI skilling and cyber resilience programs. The first workshop runs in Singapore this October, at Singapore International Cyber Week.
Come build with us
None of this happened alone. Partners like CyberPeace in India and Code for Japan helped turn open models into working tools. If you run a national AI program, a cyber agency or critical infrastructure, and you'd like more options than you have today, write to us at [email protected]. Request access to EuroLLM and Apertus, or start with the harness.
A year ago, we said choice is the path to AI sovereignty. This year showed it's the path to AI security, too.