Sam James has sent an announcement
to the OSS Security mailing list about another
local-privilege-escalation (LPE) exploit in the same class as Dirty Frag, called
“Fragnesia”. From the disclosure:
This is a separate bug in the ESP/XFRM from dirtyfrag which has received its own patch. However, it is in the same surface and the mitigation is the same as for dirtyfrag.
It abuses a logic bug in the Linux XFRM ESP-in-TCP subsystem to
achieve arbitrary byte writes into the kernel page cache of read-only
files, without requiring any race condition.
James noted that there is a patch
in the works, but it has not yet been pulled into Linus Torvalds’s
tree nor into any of the stable kernels. A proof
of concept exploit is also available.
Attackers do not need to break into the front door when they can convince employees to open it for them through the tools they already trust.
In April 2026, Rapid7 investigated an enterprise intrusion that began with a Microsoft Teams message from a fake “IT Support” account and quickly escalated into a full compromise chain involving malware deployment, privilege escalation, credential theft, lateral movement, and exfiltration. The incident illustrates a critical risk for modern enterprises: Collaboration platforms have become part of the attack surface, and when combined with identity abuse and Living-off-the-Land techniques, they can provide attackers with a low-friction path into the environment.
Therefore, this attack was particularly concerning due to the way the intrusion shifted from endpoint compromise to broader identity-driven risk. And while it was not surprising that the attacker used a novel technique, what was concerning was how the attacker was able to chain together familiar enterprise weaknesses into a fast-moving and operationally effective intrusion.
By abusing Teams external access, the threat actor delivered a Dropbox-hosted Python payload that established command-and-control, deployed multiple backdoors, and began mapping the internal environment. The attacker then escalated privileges to SYSTEM using CVE-2023-36036 before deploying a fake Windows lock screen designed to harvest the user’s domain password.
Once valid credentials were obtained, the intrusion shifted from endpoint compromise to broader identity-driven risk. The attacker moved laterally to a second host, used legitimate tooling such as DumpIt to collect system memory, which was likely exfiltrated via an anonymous file-sharing service. This progression underscores a key reality for defenders: Once collaboration, identity, and endpoint controls are bypassed or weakened, attackers can rapidly convert initial access into meaningful enterprise exposure.
Rapid7’s technical analysis linked the Python malware to ModeloRAT, a framework previously documented by multiple security vendors in browser extension campaigns and associated with the KongTuke group. More broadly, this intrusion demonstrates how trusted communication channels, Living-off-the-Land techniques, and credential-focused tradecraft continue to challenge traditional security controls. The takeaways here are clear:
For CISOs: Collaboration tools are part of your attack surface. Attackers used Teams to reach users directly. Security, identity protection, endpoint visibility, and rapid detection engineering must be treated as connected parts of the same defense strategy, not separate control domains.
For defenders: Old vulnerabilities and trusted tools still work. The attack combined a patched vulnerability (CVE-2023-36036) with widely trusted tools like Python, PowerShell, and Dropbox. None of these are unusual in enterprise environments, which is precisely what allowed the attacker to blend in while moving quickly. It’s an obvious restatement, but external access should always be controlled and monitored.
The challenge isn’t identifying one suspicious event; it’s recognizing when normal activity starts to form a pattern, and acting before that pattern turns into widespread exposure.
Rapid7 coverage
Rapid7 has coverage for this campaign across both intelligence and detection workflows. The campaign is available in Rapid7’s Intelligence Hub, providing customers with curated context, indicators, and threat actor tradecraft to support awareness, investigation, and prioritization. Relevant detections are also available in InsightIDR, helping security teams identify activity associated with this intrusion pattern across their environments.
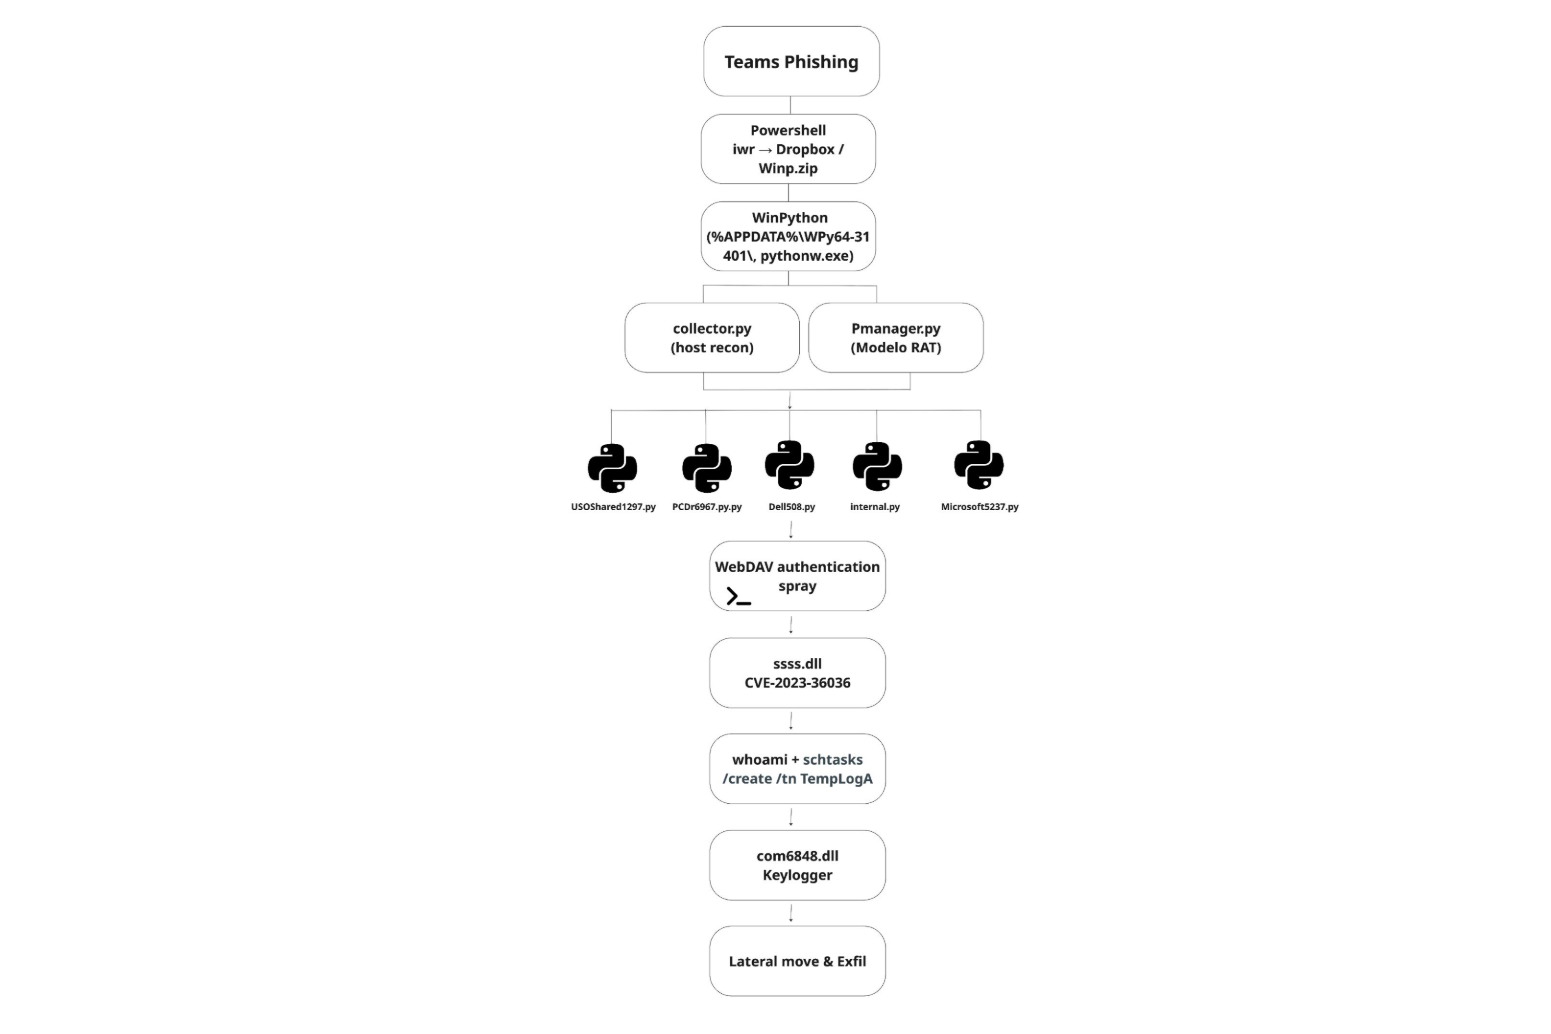
Figure 1: Attack chain from Teams phishing to payload delivery, ModeloRAT execution, privilege escalation, and lateral movement with exfiltration.
A door that was never closed
The intrusion started with abuse of Microsoft Teams external access. This feature, enabled by default in some environments, allows users in one tenant to initiate direct chats with users in another. In our incident, the attacker used a newly created tenant UCICasociacion.onmicrosoft[.]com to impersonate “IT Support” and messaged a targeted employee.
This approach mirrors tradecraft seen in Octo Tempest-style campaigns. Octo Tempest (alias Scattered Spider, UNC3944, 0ktapus) is a financially motivated cybercriminal group active since 2022, known for aggressive social engineering tactics including helpdesk impersonation, SIM swapping, and MFA manipulation.
Shortly after the interaction, a hidden PowerShell command executed on the victim’s machine, staging the initial payload.
Stager: Bring your own Python
Within minutes of the Teams interaction, a PowerShell stager executed on the endpoint and reached out to Dropbox to retrieve a ZIP archive (Winp.zip) into the user’s AppData directory.
The archive was immediately extracted and deleted, likely to reduce on-disk artifacts and avoid potentially raising suspicion.
The payload contained a portable WinPython environment, which the attacker used to launch the next stage:
collector.py (reconnaissance)
Pmanager.py (primary C2 agent, Modelo RAT)
Execution was handled via pythonw.exe, which allowed the script to run in the background without showing the terminal window.
Figure 2: PowerShell stager retrieving and executing portable Python payload.
Reconnaissance: Environment discovery via native tools
The first Python module executed by the attacker was collector.py, a post-exploitation information gatherer designed to silently profile the host and save the results to %TEMP%\configA.json. Additionally, before any of the recon the collector.py computes a host fingerprint. This 8-character fingerprint is what the operator’s C2 server uses to identify this victim.
Securityhealthhost.exe, which is commonly used to verify if anti-virus solutions are running on the system
Table 1: Host Reconnaissance and Environment Enumeration.
All of these commands were executed through hidden PowerShell sessions using the CREATE_NO_WINDOW flag, allowing the script to run in the background without spawning visible console windows.
Part of reconnaissance was also a collection of installed hotfixes and system version data. The attacker was able to assess whether the host was vulnerable to a version-specific local privilege escalation exploit later used in the intrusion.
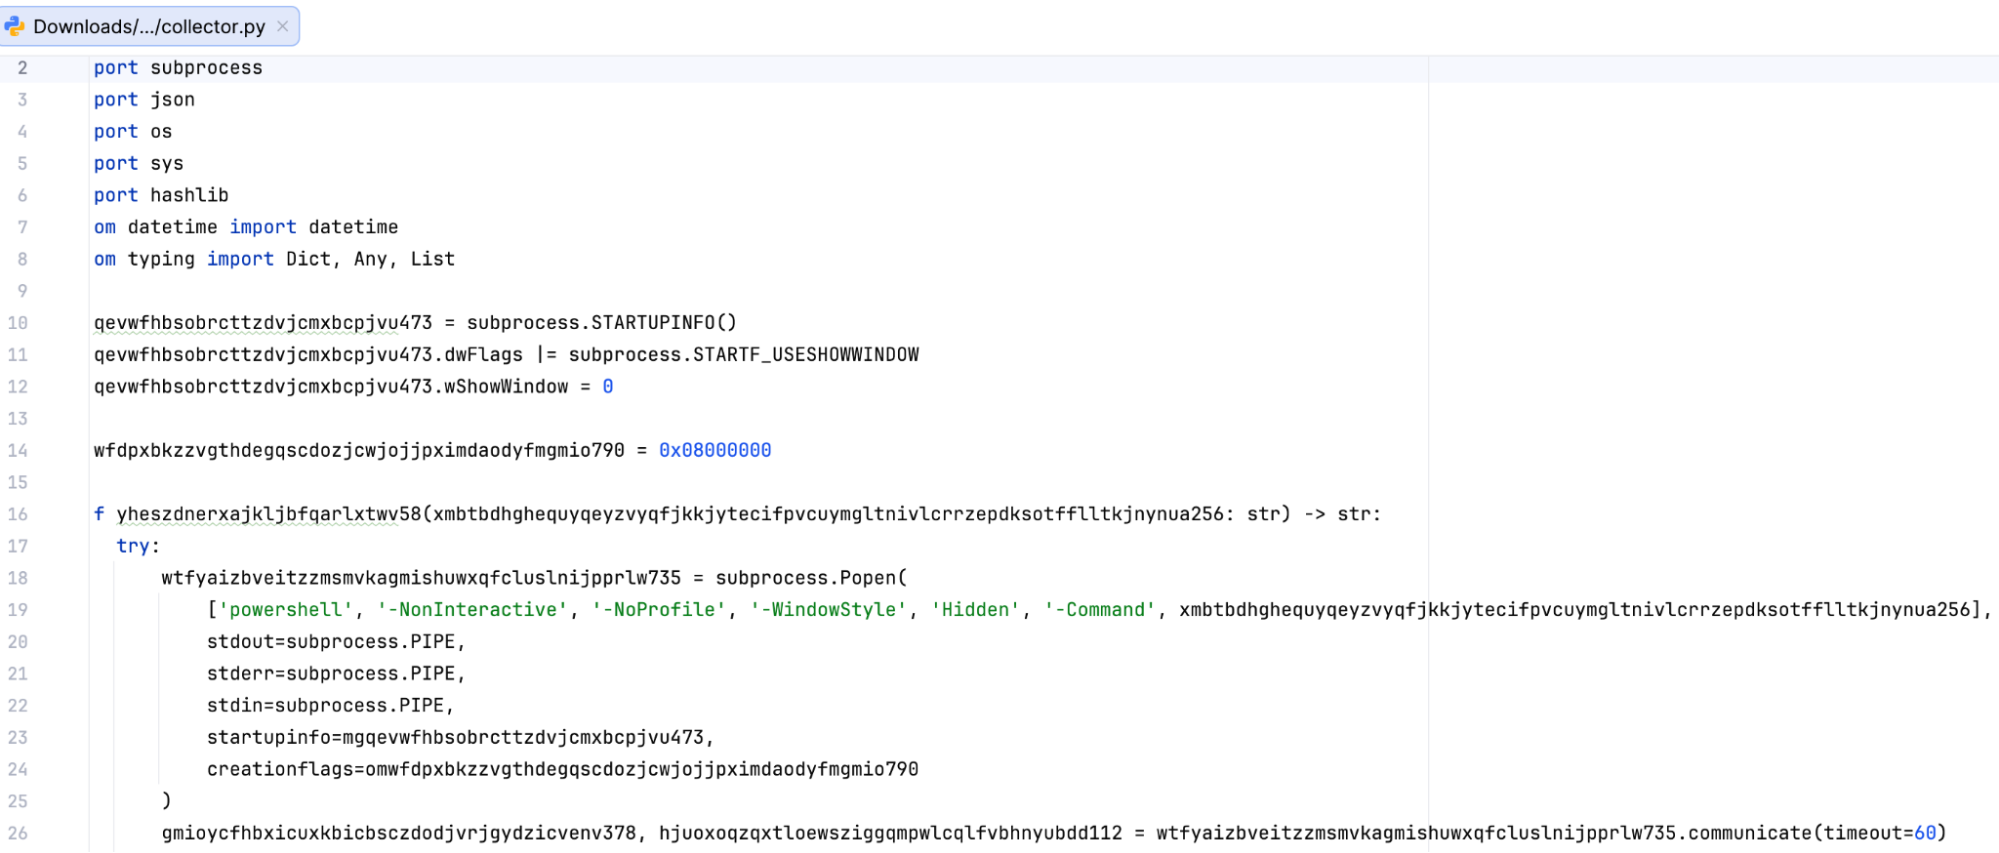
Additionally, collector.py and all other python modules dropped by malware were obfuscated. However, it was not difficult to recover code structure close to the original.
Figure 3: Obfuscated collector.py
Stage 2: Ties to ModeloRAT
Shortly after reconnaissance is completed, the attack shifts into its second stage as with the execution of Pmanager.py.
pythonw.exe ...\python\Pmanager.py start
Figure 4: Execution of Pmanager.py initiating second-stage C2 activity.
As soon as it is started, the script creates a long-running HTTP beacon over port 80 that rotates across 5 hardcoded C2 servers: 46.225.231[.]170, 144.172.99[.]68, 64.94.85[.]158, 140.82.6[.]45, and 45.76.241[.]51.
The script can load DLLs via rundll32.exe, launch additional Python scripts, run PowerShell commands, or install .msi packages. It also handles persistence and can update or remove itself. The reconnaissance output saved in configA.json is sent back to the C2, giving the operator a full picture of the host before issuing further tasks.
This behavior closely matches the ModeloRAT framework documented by Huntress (KongTuke / CrashFix campaigns). Its communication format, persistence mechanisms, and delivery model all match what has been previously observed, with no significant deviations.
The key difference is in initial access: Where earlier campaigns relied on malicious browser extensions, this intrusion used Microsoft Teams social engineering to achieve execution.
The on-demand shells and the WebDAV
Pmanager quickly deployed its first additional module USOShared1297.py onto the infected host. This module is a TCP reverse shell that opens 2 outbound sockets to one of 3 hardcoded C2 IPs (144.172.88[.]18, 64.190.113[.]187, 45.59.122[.]231. The port 50508 is reserved for the interactive shell that the attacker can use and port 60503 is for file transfer. The shell itself is a cmd.exe spawned using CreatePipe and CreateProcessA with the CREATE_NO_WINDOW and STARTF_USESTDHANDLES flags.
This access was then used to test credential reuse across the environment through repeated WebDAV authentication attempts against internal systems.
Figure 5: WebDAV authentication spray using davclnt.dll (DavSetCookie)
The DavSetCookie API forces Windows to initiate a WebDAV authentication attempt using the current user’s credentials. In effect, it allows the attacker to validate where those credentials are accepted without deploying additional tools. Within minutes, successful logon events started to appear across more than 100 internal systems.
The HTTP shell – internal.py
Not long after, the attacker added a second way into the system by deploying back-to-back Microsoft5237.py dropped to %TEMP% and internal.py dropped to WPy64-31401\python. Later analysis showed they were actually the same file, just renamed (both had the same SHA-256 hash: 930263c0843744e269b615fb2ec79f83d7bd8b2cbf75e31fd5ea6c1aaa4e48fd). The attacker was reusing the same backdoor under different names.
Each script launched a hidden PowerShell session. First it checked whether the system was domain-joined, and then set up a persistent remote shell.
Figure 6: The -NoExit flag keeps PowerShell running in the background, while the trailing “-” allows it to accept commands remotely.
From there, internal.py turned that session into a full HTTP-based control channel. It registered with the C2 /handshake, continuously polled for instructions via /command/<id>, executed them inside the PowerShell session, and returned output via /output/<id>. The same channel handles file upload, download, and also screenshot capture. All of this communication ran over port 80 to 87.120.186[.]229 and 149.248.78[.]202, blending in with normal web traffic.
Stage 3: Privilege escalation via CVE-2023-36036
After gaining remote access, the attacker executed ssss.dll to escalate privileges.
rundll32.exe ssss.dll startproc Mw2[REDACTED]
Figure 7: Execution of ssss.dll via rundll32.
The argument that was passed to startproc is a decryption key. The startproc function uses Mw2[REDACTED] to decrypt the payload.
The ssss.dll (SHA-256: b00c1cbcfb98d2618a5c2ccb311da94f3c57709a397be6c8de29839f4e943976) is a reflective loader. The loader is using that key to decrypt an embedded payload in memory and execute it. The decrypted payload is testdllLPE.dll (SHA-256: d84245f3a374dd5eff8ecfdfad39077d76331fde799e5306430d0fc788db7f1d), a custom privilege escalation exploit targeting CVE-2023-36036. This vulnerability is a heap-based buffer overflow in cldflt.sys, the Windows Cloud Files Mini Filter Driver.
Within seconds, the helper thread launched internal.py under a SYSTEM token, confirming that the exploit successfully modified the process privileges.
What is CVE-2023-36036?
The Cloud Files driver is what makes OneDrive’s “Files On-Demand” work, allowing placeholder files to appear locally while being backed by cloud storage. Sync providers (OneDrive, Dropbox, Box) register themselves with the driver using the Cloud Files API, and the driver brokers I/O between the filesystem and the provider.
CVE-2023-36036 is a heap buffer overflow in how cldflt.sys processes messages from these providers. By sending crafted data through the driver’s communication interface, an attacker can overflow an internal buffer and corrupt adjacent memory. With controlled heap layout, this corruption becomes a kernel write primitive.
Reused technique, adapted exploit
While analyzing the CVE-2023-36036 exploit, it became clear that the threat actor did not build their methodology from scratch. STAR Labs documented a similar chain in their analysis of CVE-2021-31969 also in cldflt.sys. Their work outlined the core steps: Register a fake sync provider, shape the kernel heap, trigger the overflow, and overwrite a token.
The exploit we analyzed follows the same general playbook, but adapts it for the CVE-2023-36036 vulnerability.
The threat actor reused three core steps from the STAR Labs research to stabilize their exploit:
Sync provider registration. The exploit registers itself as “PLURIBUS” with GUID {904EE598-0511-4664-82A8-22C4A7501044}, pointing to %TEMP%\cldflt. This causes the driver to treat the directory as a valid Cloud Files root and route file operations through the vulnerable path.
WNF heap shaping. The exploit uses 4 undocumented ntdll syscalls: NtCreateWnfStateName, NtUpdateWnfStateData, NtDeleteWnfStateData, and NtQueryWnfStateData to allocate a large number of small objects in the kernel pool. This shapes memory so the overflow lands on controlled data instead of random structures. Without this step, the buffer overflow in cldflt.sys would write to unpredictable addresses and can crash the system
Data-Only Token Overwrite. Instead of using process injection or shellcode, the exploit uses its own token in kernel memory by flipping a privilege bit to gain SYSTEM access. What sets testdllLPE.dll apart is what the operator added on top of that scaffolding.
Kernel discovery method. It probes the kernel address range in 1 MB steps, measuring minute differences in memory access latency to identify ntoskrnl base. This avoids calling privileged APIs.
Decoupled execution model. Instead of elevating the thread running the exploit, this binary spawns a helper thread that continuously polls PrivilegeCheck(SeDebugPrivilege). This allows the main exploit thread to crash, hang, or retry the kernel write multiple times without losing the payload. The moment the kernel finally flips the privilege bit, the helper thread detects the change and immediately launches internal.py as SYSTEM.
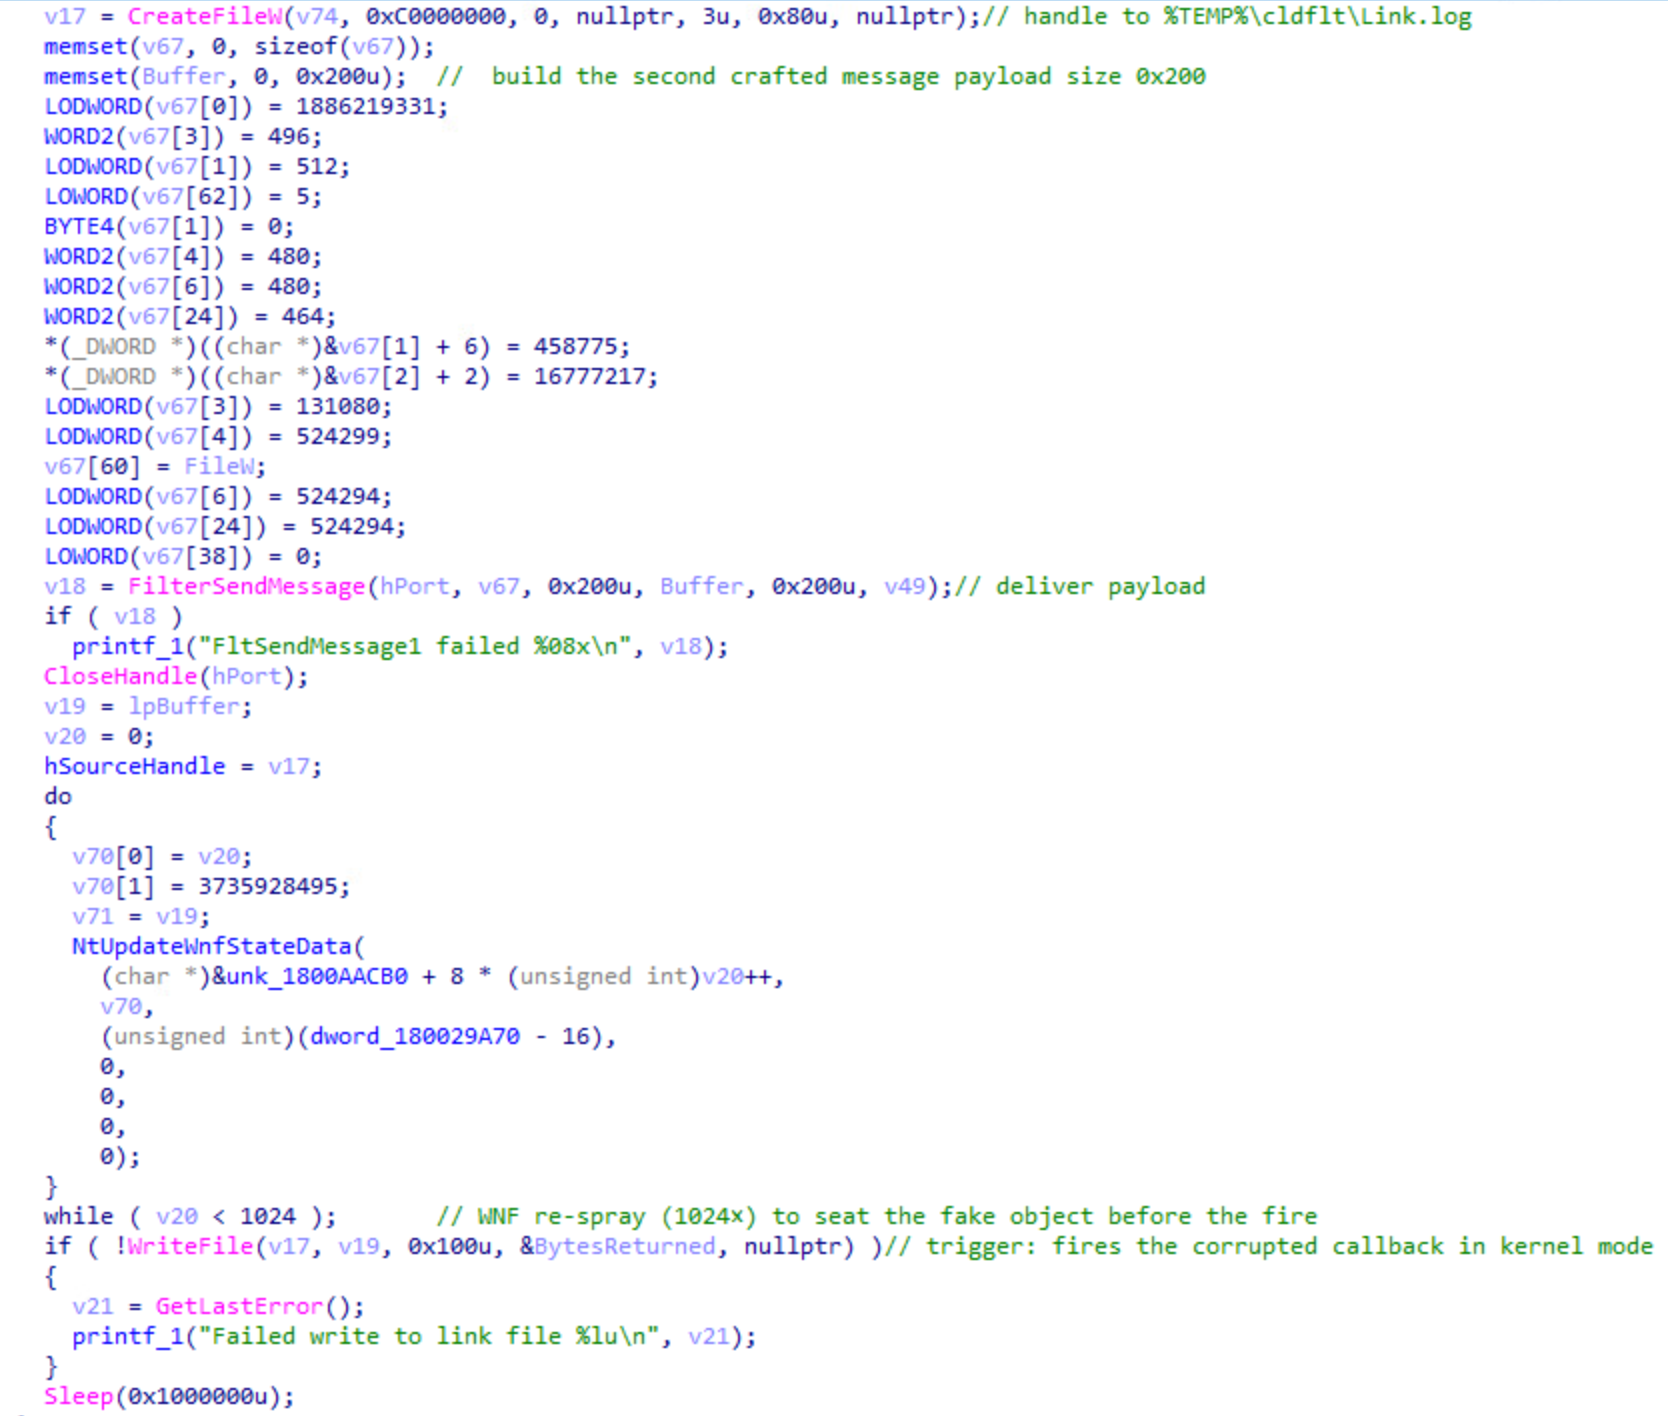
Trigger path. The vulnerability is reached through the driver’s message handling path. When processing a FilterSendMessage request, cldflt.sys copies attacker-controlled data into a fixed-size buffer without proper bounds checking, overflowing into adjacent memory, specifically a function pointer.
To trigger execution, the exploit creates a placeholder file within the fake sync root and writes to it.
Figure 8: CVE-2023-36036 trigger sequence in startproc. A crafted 512-byte message is delivered via FilterSendMessage, a 1024-iteration WNF spray seats the fake kernel object, and the closing WriteFile fires the corrupted callback.
⠀
When the driver intercepts the write to Link.log, it invokes the corrupted function pointer. This results in a controlled kernel write, which flips the SeDebugPrivilege bit in the helper thread’s token.
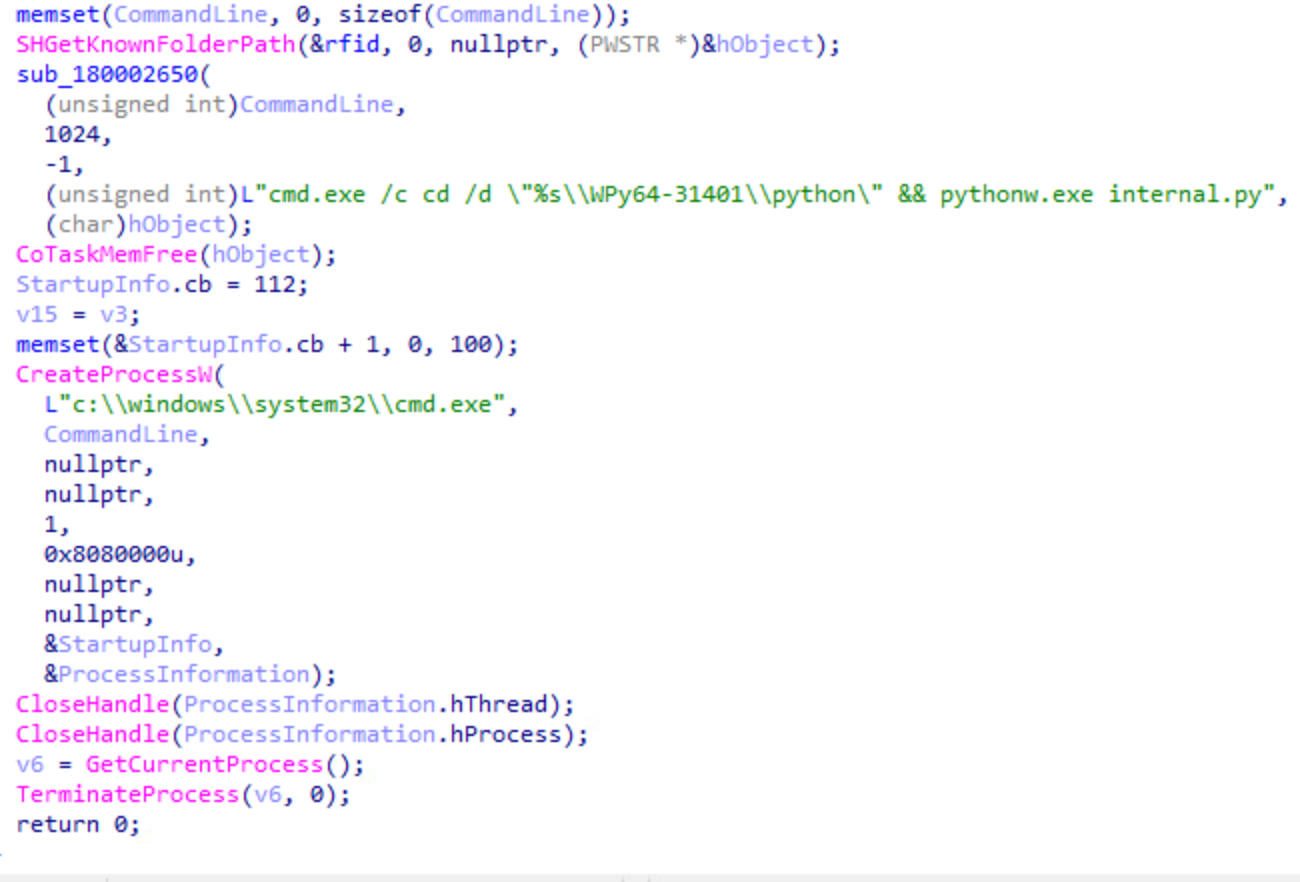
After the WriteFile call completes, the main exploit thread exits. The helper thread, which was polling PrivilegeCheck(SeDebugPrivilege) once per second since the exploit started, detects the change and breaks out of its loop. At this point, the privilege escalation has succeeded. The helper thread immediately launches the payload.
Figure 9: Helper thread execution after privilege escalation succeeds.
⠀
Stage 4: Post-exploitation
The newly spawned internal.py process was running under a SYSTEM token. The attacker confirmed this with whoami and immediately created a scheduled task (TempLogA) to execute internal.py daily at 13:00 with SYSTEM privileges.
Figure 11: Powershell command returns the total number of domain user accounts.
Shortly after, the compromised account established a remote PowerShell session (WinRM) to a second host. Once connected, additional enumeration commands were executed through the remote PowerShell process (wsmprovhost.exe), extending visibility beyond the initial system.
Expanding the foothold
Within hours of privilege escalation and enumeration, 3 additional Python modules were deployed:
Microsoft5237.py: HTTP beacon to 87.120.186.229 and 149.248.78.202. Captures screenshots via PowerShell, monitors user logins/logouts, uploads files to C2.
Dell508.py: Reverse TCP tunnel to 207.246.114.50 and 149.28.96.170 on port 80, disguised as HTTP upgrade. C2 server instructs victim to connect to specific internal targets; victim relays traffic bidirectionally.
PCDr6967.py: SOCKS5 proxy to 96.9.125.29, 144.172.111.49, and 104.194.152.246 on port 50504. Routes attacker’s tools (RDP, browsers, Nmap) through victim into internal network.
Stage 5: The lock screen that wasn’t
Roughly two hours after privilege escalation, the attacker deployed a second DLL.
rundll32.exe com6848.dll,open e8vy[REDACTED]
Figure 12: Execution of com6848.dll via rundll32 to deploy credential harvesting payload.
The com6848.dll (SHA-256: 30e5a6c982396cdf3157195b540f75096869baa8570f66fab88c07c161be27f0, internal name apple.dll) is a 32-bit DLL with a single export open. Its .rdata section is over 5 MB and contains an encrypted payload. The decryption key was conveniently provided on the command line by the attacker.
Once decrypted, the DLL reflectively loads a second stage stage2.dll (SHA-256: f5b2dbd8ec9671c0261f093ebc5f3d35920b592458a3b800cc946265111e67d0). This DLL renders a perfect replica of the Windows 10 lock screen, using the embedded font to ensure visual accuracy even on systems where the font isn’t installed. The user sees what appears to be a normal screen lock and types their password to unlock it. The DLL captures it, and writes the result to disk as yyyy-mm-dd-Log.txt
What the credential unlocked
Wait, didn’t the operator already have SYSTEM privileges? Why bother with a fake lock screen?
By this point, indeed the operator had SYSTEM-level access on the host. What they didn’t have, though, was the user’s domain credentials. SYSTEM can authenticate using the machine account, but it cannot authenticate as the user. It can’t access user-specific resources, such as file shares requiring the user’s permissions, mailboxes, web applications expecting user credentials, or RDP sessions that need to establish an interactive logon as that specific domain account.
The same evening, the attacker used harvested credentials to authenticate via RDP to another workstation in the network. DNS logs showed connections to Dropbox and some internal systems. Additionally, they also performed Kerberoasting against service accounts, requesting vulnerable Kerberos tickets in an attempt to expand access within the environment.
The following morning, the attacker returned to the second host via RDP and used Microsoft Edge to download the Comae toolkit, including DumpIt, a legitimate memory acquisition tool. Two minutes after unarchiving the Comae toolkit, the threat actor navigated within the browser to uploadnow[.]io, which offers free anonymous file upload features. During this browser session, the threat actor searched via Bing if SwissTransfer was a safe site to transfer large files, likely evaluating additional exfiltration methods.
Shortly after, DumpIt.exe was executed on the second host. DumpIt captures physical RAM, including LSASS process memory, which can contain cleartext passwords, NTLM hashes, and Kerberos tickets. Based on timing and network activity, the memory dump was likely exfiltrated via uploadnow[.]io.
Fake lock screens can harvest credentials even with SYSTEM access.
WebDAV API abuse provides stealthy credential validation.
It took two days to go from “Hi, this is IT support” to domain-wide credential access using a fake lock screen, a Python based RAT, and a two-year-old kernel exploit. If you were an incident responder, none of these techniques would have been new for you, and that’s the point.
What particularly stands out is how quickly control shifted from endpoint to identity. Once valid credentials were obtained, the environment itself became the attack surface.
When Brendan Jackman proposed
a session for the 2026 Linux Storage,
Filesystem, Memory Management, and BPF Summit, his topic was “a
pagetable library for the kernel“. During the actual
memory-management-track session, though, he stated that the idea had
“fizzled” and he was going to cover related topics instead. What
resulted was a session on ways to efficiently manage pages that are not
present in the kernel’s direct map.
At Rapid7, our commitment to our partners is built on the foundation of the PACT (Partnering with Accountability, Consistency, and Transparency) program. Central to this mission is the Rapid7 Partner Academy, which was recently honored with a Gold Stevie Award in the 2026 American Business Awards® for Achievement in Collaboration and Partnership. This recognition underscores our dedication to providing world-class training that translates directly into partner success and customer resilience.
A new era of partner-led services
To meet the evolving needs of the cybersecurity landscape, Rapid7 Partner Academy has introduced specialized Partner Services Certifications. These role-based learning paths are designed to move beyond traditional “product training” by focusing on high-fidelity service delivery and outcome-driven results, including how to build, deliver, and scale services on Rapid7 solutions. The training and certification program was specifically recognized for its “Partner-First” design, which was built through extensive collaboration with our global partner ecosystem to ensure alignment with real-world sales and technical challenges.
Our award-winning partner services certification ecosystem focuses on three critical pillars of the Rapid7 Command Platform:
Partner Services for InsightIDR: Equips partners with the skills and knowledge necessary to effectively guide customers through the post-sale phases of the InsightIDR solution.
Partner Services for Exposure Command: Focuses on the transition from static vulnerability scanning to continuous attack surface validation, diving into the setup, management, and troubleshooting of Exposure Command.
Partner Services for Vulnerability Management: Empowers partners to provide impactful services around deployment, management, and ongoing support for InsightVM that drive customer success.
All three of these Partner Services Certifications enable our partners to deliver services around Rapid7 solutions from deployment and onboarding, to management and best practices for usage, to express health checks and troubleshooting. Upon successful completion of the course theoretical exam, you are eligible to enroll in the Services Validation Component. After validating your services capabilities, you will receive the prestigious distinction of achieving the Rapid7 Partner Services Certification and Badge. This achievement helps to differentiate your services to your customers and prospects with official recognition among the most capable Rapid7 MSSPs and service delivery partners.
Real-world impact: From training to execution
The Gold Stevie Award recognizes more than just curriculum—it recognizes the impact these certifications have on the partner’s ability to drive business and accelerate their profitability with Rapid7. By completing these Rapid7 Partner Academy certifications, partners gain:
Operational excellence: Technical specialists learn to deploy and manage Rapid7 solutions with a “Gold Standard” approach, ensuring high-fidelity results for customers.
Strategic alignment: Sales professionals are trained in the RSP (Rapid7 Sales Professional) methodology, allowing them to position Rapid7 as the preferred solution through effective discovery and objection handling.
Program economics: Certified partners can take full advantage of the 2026 PACT updates, which offer enhanced incentives and streamlined deal motions for partner-led growth.
Collaborating for success
The Stevie Award for Achievement in Collaboration and Partnership specifically applauds how Rapid7 integrated partner feedback into the curriculum development. This wasn’t just Rapid7 talking to partners; it was a co-innovation effort. By coordinating with partners and Rapid7 technical support stakeholders, we ensured that the Partner Academy content directly addresses the “last-mile” technical blockers partners face in the field.
The value and impact of Partner Academy is highlighted by the comments from the Stevie American Business Awards® judges:
“I’ve seen a lot of partner programs, and most are built for the vendor, not the partner. This one stands out…A 5X outperformance, 76% completion rate, 91% satisfaction, and an NPS of 68 all point to real value delivered, not vanity metrics. I’m especially impressed by the coordination behind it –100 contributors across 13 business units. That level of alignment is hard to achieve, and it shows strong leadership. The fact that the program was mentioned on an earnings call also signals clear strategic impact.”
“Overall, this is an outstanding and result-oriented program, and it sets the bar high for the partner enablement process. Exceeding the certification target by 5X within a significantly shortened timeframe speaks volumes for the relevance and execution of the program, and the creation of role-based, technically sophisticated learning paths speaks volumes for the focus on partner enablement.”
Celebrating our partners
This award is a shared victory with the thousands of partner individuals who have invested in their professional development through the Partner Academy. Whether you are a technical expert seeking to “Command the Attack Surface” or a sales professional looking to protect your margins, the Partner Academy is your gateway to success in the Rapid7 ecosystem.
Join the award-winning program and start your learning journey today!
As we continue to innovate, our goal remains the same: to provide the most transparent, consistent, and world-class enablement program in the industry. We invite all partners to officially become a Rapid7 PACT Partner to explore these award-winning certifications and start driving deeper impact for your customers today.
Linux can share memory between processes, but each process (almost always)
has its own set of page tables. In situations where vast numbers of
processes are sharing a memory region, the combined size of the page
tables can exceed that of the shared memory itself. There has, thus, long
been an interest in enabling unrelated processes to share page tables
referring to shared memory. Anthony Yznaga is the latest developer to try
to push this idea (known as “mshare”) forward; he described the status of
that work in a memory-management-track discussion at the 2026 Linux Storage,
Filesystem, Memory Management, and BPF Summit (LSFMM+BPF).
The KDE project has announced
that it has been awarded over €1 million from the Sovereign Tech Fund
to improve its desktop-environment software. “The investment will be
used to strengthen the structural reliability and security of KDE’s core
infrastructure, including Plasma, KDE Linux, and the frameworks underlying
its communication services.“
We’ve enabled higher usage limits, faster performance, and better reliability for Browser Run by rebuilding on top of Cloudflare’s Containers.
You can now spin up 60 browsers per minute via the Workers binding and run up to 120 concurrently — 4x the previous limit. Also, Quick Action response times dropped more than 50%. You don’t need to change anything: these improvements are live today. On top of that, we’re shipping fixes and new features faster than before. Read on to learn how we did it and see the data.
Remind me: what is Browser Run?
Browser Run enables developers to programmatically control and interact with headless browser instances running on Cloudflare’s global network. That’s useful for end-to-end testing of web applications, securely investigating suspicious URLs, and leveraging how browsers can easily render PDF documents, amongst other quick actions like capturing screenshots and extracting content. More recently, it’s become a critical enabler of AI agents to interact with the web. We’re building Browser Run to be the go-to platform to responsibly utilize automated browsers securely at massive scale.
Outgrowing our bunk bed
Before adopting Cloudflare Containers, we shared infrastructure with Browser Isolation (BISO). While technically similar, BISO’s larger container images slowed startup and development. Crucially, BISO browsers lacked optimal global distribution, compromising resiliency and latency. Additionally, typical BISO users’ long, steady sessions clashed with Browser Run’s short, spiky usage, creating scaling bottlenecks and availability delays.
Thankfully, after much internal development, Cloudflare released Durable Object (DO)-enabled Containers open beta last year, meaning we were ready for a tentative adoption that ultimately benefited both product platforms. Like most successful product platforms, we’re committed to building on our own platform wherever feasible so that we can feel and fix any pain points ahead of any external customers.
The migration: Containers
We started a gradual migration by inserting a Worker in our incoming request paths to provide some Container-powered browsers to a handful of users alongside those from BISO. This dual support during development was key: it allowed us to compare performance, isolate implementation bugs and ultimately gain confidence in the benefits of the Container-driven approach.
Ramping up adoption, we first used the Container browsers for all of our Quick Actions endpoints, then for connections via the Workers browser binding on free accounts, followed by pay-as-you-go accounts in order to validate stability before we rolled it out to all remaining contract customers, ensuring a transition that required no action or existing worker redeployments from our customers.
Challenges: performance and scale bottlenecks
On our end, though, we faced a fresh set of challenges getting familiar with a novel, unstable early-stage Containers platform interface that was light on documentation, light on observability, and light on colleagues in an overlapping timezone. However, our feedback to our own teams as Customer Zero meant that we could provide a tight feedback loop leading to substantial upgrades that benefit our external customers too. Nevertheless, there was a lot of friction to overcome initially, most of which were to be expected for a closed beta in active development. Other hurdles to overcome were intrinsic to the new technical environment.
For example, once our browsers could run globally, our architecture had to adapt. DO-enabled Containers create a Durable Object as close to the incoming request as possible, but the connected Container may spin up on the other side of the world. This works fine for one-shot messages like “start my app,” but when you’re establishing a WebSocket between them and exchanging dozens of messages for a screenshot request, those extra milliseconds crossing the globe start adding up.
Our solution? Create regional pools of pre-warmed DO-backed browser containers to constrain the max distance (and hence max latency) between DOs and containers. When a request comes in, we pick a DO-container pair closest to the user within that region. This keeps latency low on both hops: user to DO, and DO to container. It adds a few more moving parts to our overall architecture, but we figured that was worthwhile so long as we had observability into the global state of each browser so that we could allocate and re-allocate capacity according to changing demand. A perfect use case for Workers KV…to a point.
Demand for our headless browsers has been ramping up since the beginning of last year. In short, AI agent builders discovered Browser Run and quickly brought request volumes outpacing our existing capacity. We quickly hit the limits of how quickly we could adjust our pool capacity to serve this new demand with a scalable approach. KV’s eventual consistency of around 30 seconds was becoming a bottleneck on our critical request path. You might check KV, see a container as “available,” but by the time you route to it (30 seconds later), it’s already claimed. That lag creates race conditions and overallocation of browsers, severely limiting how fast we could scale to meet demand spikes.
Migrating from KV to D1 + Queues
We previously stored each container state in KV. This meant that we could keep getting a minute old state due to cache TTL (recently KV changed the minimum cache TTL to 30 seconds, but even so that value is still too high).
We decided to migrate the container state into D1 instances instead. D1’s transactional nature is a good fit here. Once we assign a browser to a user, it’s exclusively theirs. Browsers are not shared resources. SQLite transactions ensure atomic assignment and prevent race conditions where two requests might claim the same browser simultaneously.
Here’s a simplified version of our browser acquisition query:
WITH candidate_pool AS (
    -- candidate pool logic to pick based on latency and other rules
)
UPDATE containers
SET status = 'picked'
WHERE sessionId IN (
    SELECT sessionId
    FROM candidate_pool
    ORDER BY RANDOM()
    LIMIT ?5
)
RETURNING data
We keep D1 shards per location and given that we may have several thousand containers running, and that each container needs to update its state every 5 seconds, we kept running into a problem: we would overload the database. For instance, if each write takes 1ms we can only write at most 1,000 times, which at one row per write would mean that we could only have 5,000 containers before overloading the database.
However, if we batch those writes, we can get much higher values, because batch writes are not significantly longer than individual ones, so we can increase the throughput in orders of magnitude. In our case, we use 100 row batches, which means we can now update a maximum of 500,000 containers per location. This headroom means capacity planning is no longer a bottleneck.
Currently, our P95 for batch write is 0.1ms!
To batch writes, we use Queues: every 5 seconds, each container computes its own state and adds it to its location queue. We then configure a worker consumer with 100 batch size and 1 second batch timeout:
With this configuration, we achieve acceptable lag times well below 2 seconds. That said, queue backlogs can still cause stale state. When this happens, each region falls back to a designated backup region until the primary queue catches up.
Additional perks for quick actions
With dedicated infrastructure, we could now make upgrades to the browser container image without unwanted side effects or bloat for other products like BISO. This opened the door to optimize quick actions like screenshots and content extraction. Previously, our workers established a WebSocket to the remote browser and sent instructions one at a time: open a page, navigate to the URL, wait for it to load and take the screenshot. Each step had to be completed before the next could begin.
However, now we send all parameters in a single HTTP request directly to the container, and the entire flow executes internally without any back-and-forth between the worker and browser.
Results: massive performance boost and increased limits
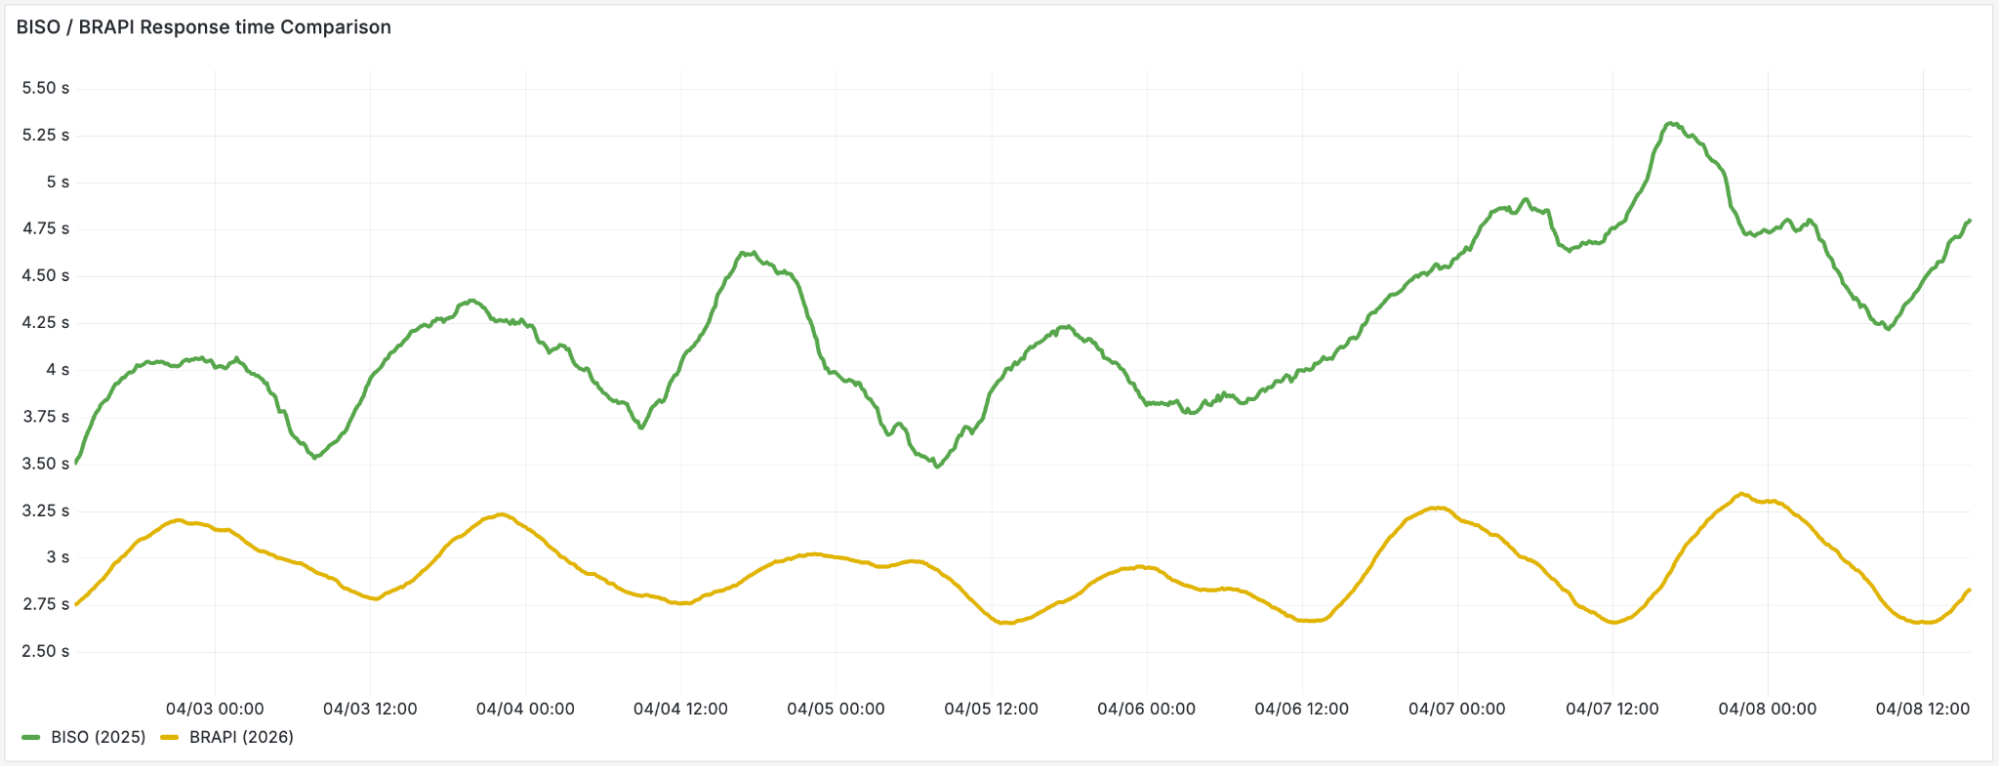
We’ve seen a sharp decrease in average quick-action response time, as users are able to get what they need from a browser session in less time: less time waiting for browsers to be ready and faster processing of their DevTools Protocol messages.
Overcoming our real-time state management at this new scale meant we could spend more time in the playground, discovering and cooking up new features such as our recently launched /crawl endpoint.
Better browser flexibility
We also benefitted from another important perk by leaving behind shared Browser Isolation containers: faster upgrades.
When our browsers ran on shared product infrastructure, upgrading Chrome meant coordinating across multiple teams and products, each with their own roadmap and priorities. However, now that we run our own container image, we can upgrade at a faster tempo. For example, WebGL, a much-requested feature, is now available for browser-based rendering along with WebMCP (Model Context Protocol for the web) which enables new agentic interaction patterns. Both are made possible because we can control the browser version and flags without unwanted side effects in other Cloudflare products.
In a nutshell, we’re just getting started with unleashing the power of browsers at scale, especially for agentic development. We hope you’re diving in too — check out our docs.
Get started
Browser Run is available on all Workers plans. Start with the quick start guide, explore the Quick Actions, or try the /crawl endpoint to deeply extract data from any webpage, following links across the site.
Building AI agents? Check out our Agents SDK with built-in Browser Run support.
The UK’s AI Security Institute evaluated GPT-5.5’s ability to find security vulnerabilities, and found that it is comparable to Claude Mythos. Note that the OpenAI model is generally available.
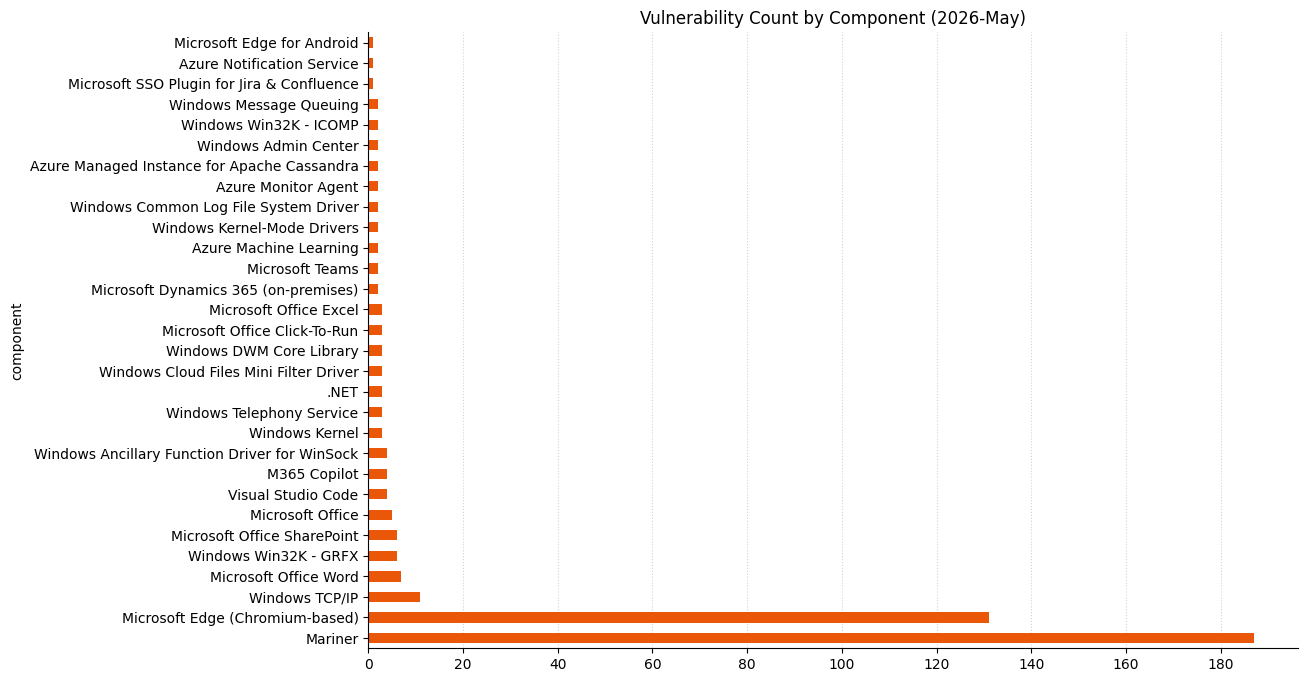
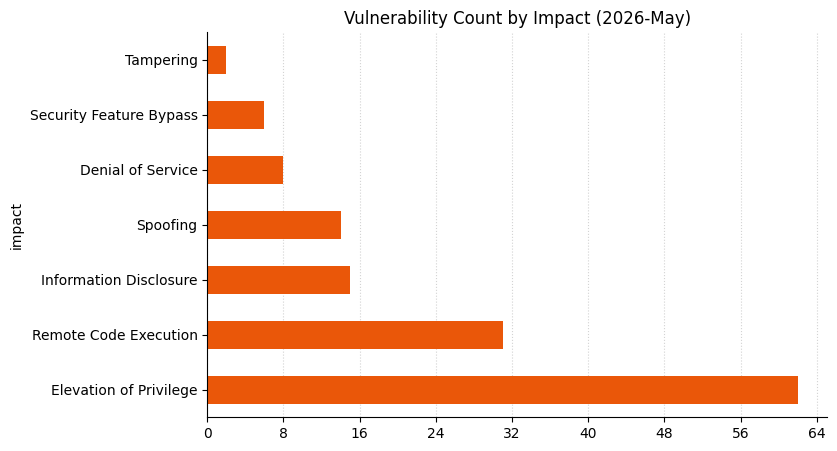
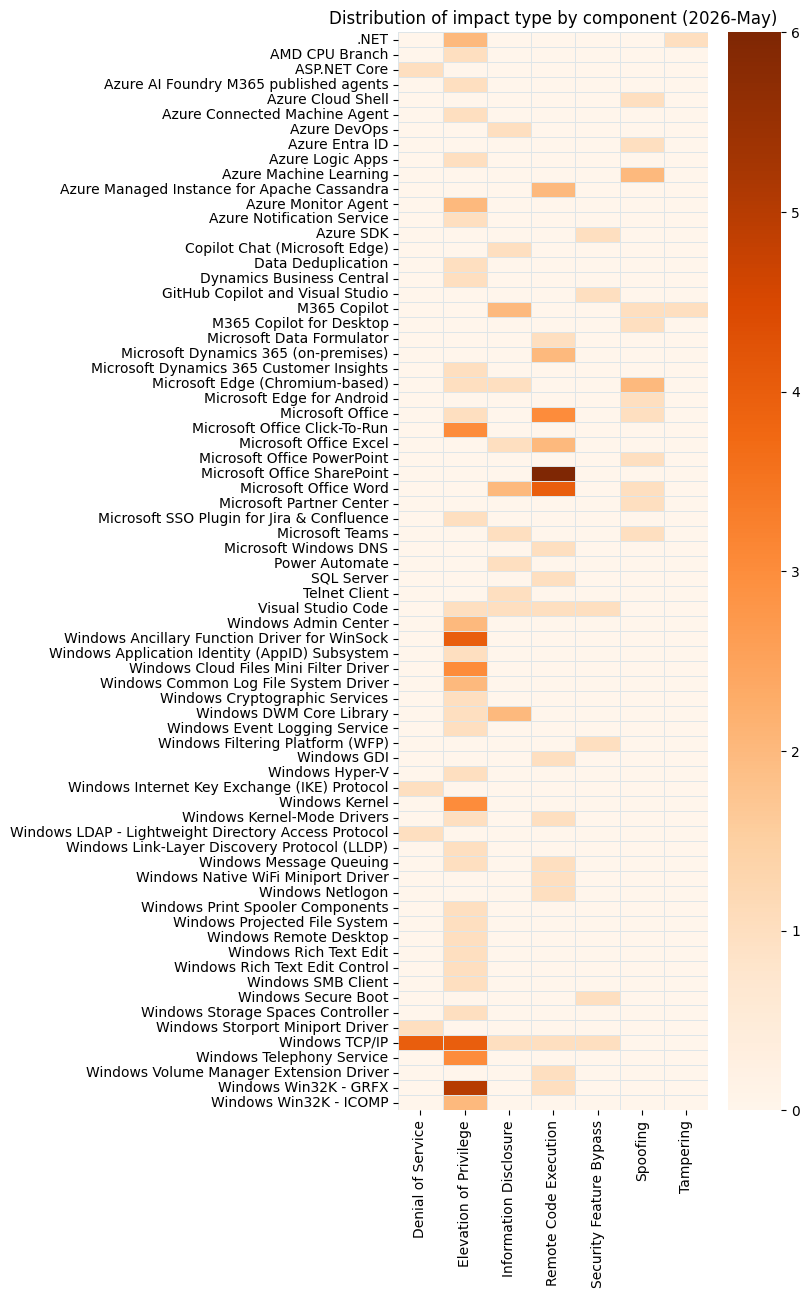
Microsoft is publishing 137 vulnerabilities on May 2026 Patch Tuesday. Microsoft is not aware of exploitation in the wild or public disclosure for any of these vulnerabilities. So far this month, Microsoft has provided patches to address 133 browser vulnerabilities, which are not included in the Patch Tuesday count above.
Windows Netlogon: critical RCE
Anyone responsible for securing a domain controller should prioritize remediation of CVE-2026-41089, which is a critical stack-based buffer overflow in Windows Netlogon with a CVSS v3 base score of 9.8. Exploitation leads to execution in the context of the Netlogon service, so that’s SYSTEM privileges on the domain controller. For most pentesters, that’s the point at which the customer report more or less writes itself. No privileges or user interaction are required, and attack complexity is low, which suggests that creation of a reliable exploit might not be especially difficult for anyone with knowledge of the specific mechanism.
Microsoft assesses exploitation as less likely, but since those exploitability assessments are provided without an accompanying explanation, it’s not clear how much reassurance defenders should take. Anyone who remembers the much-discussed CVE-2020-1472 (aka ZeroLogon) back in 2020 will note that CVE-2026-41089 offers an attacker more immediate control of a domain controller. Patches are available for all versions of Windows Server from 2012 onwards.
Windows DNS Client: critical RCE
An attacker looking for a master key for Windows assets will pay attention to CVE-2026-41096, a critical RCE in the Windows DNS client implementation. A modern computer talks to DNS the way a child in the back of a car asks “are we there yet?” The variable and complex structure of DNS responses means that DNS client implementations are also complex and thus prone to flaws. Microsoft assesses exploitation as less likely, and we can hope that modern mitigations such as heap address randomization and optional-but-recommended encrypted channel DNS will make weaponization significantly more challenging by putting barriers across specific paths to exploitation. The DNS client on Windows runs as the NetworkService role, rather than SYSTEM, but a foothold is a foothold, and skilled attackers expect to chain exploits together.
JIRA/Confluence Entra ID auth plugin: critical EoP
If you’re still self-hosting Atlassian JIRA or Confluence and relying on the Microsoft Entra ID authentication plugin, you’ll want to know about CVE-2026-41103. This critical elevation of privilege vulnerability allows an unauthorized attacker to impersonate an existing user by presenting forged credentials, thus bypassing Entra ID. Microsoft expects that exploitation is more likely. Even if you can’t always find what you want on the corporate Confluence, a motivated attacker probably will. Curiously, the patch links on the advisory lead to older versions of the plugins published in 2024.
Microsoft WARP team
Microsoft’s WARP team is credited with multiple critical vulnerabilities today, after making their first appearance in MSRC advisory acknowledgements in last month’s Patch Tuesday. We can speculate that they likely know a great deal about the current state of AI-powered vulnerability research as it applies to Microsoft products.
Microsoft lifecycle update
There are no significant Microsoft product lifecycle changes this month. Microsoft .NET 9 STS (Standard Term Support, as distinct from Long Term Support) was originally scheduled to move past the end of support in May 2026, but late last year, Microsoft granted a six-month extension, so that .NET 9 STS now reaches end of support on November 10, 2026.
Today, we’re excited to announce the preview release of full repository code review, a new capability in AWS Security Agent that performs deep, context-aware security analysis of your entire code base. AI-driven cybersecurity capabilities are advancing rapidly. AWS Security Agent can now find vulnerabilities and build working exploits across your entire code base at a scale and speed we haven’t seen before, reasoning like a human security researcher, but operating at machine velocity. Unlike traditional static analysis tools that match code against known vulnerability patterns, full repository code review reasons about your application’s architecture, trust boundaries, and data flows the way a human security researcher would and then produces developer-ready findings with transparent evidence and concrete remediation.
AWS is prioritizing free early access for customers, giving defenders the opportunity to strengthen their code bases and share what they learn so the whole industry can benefit.
The challenge: Security analysis that scales with your code
Development teams today face persistent tension. Traditional static application security testing (SAST) tools are fast and reliable at catching known patterns such as a SQL injection sink, an unescaped output, or a hard-coded credential. But modern applications are complex systems of services, APIs, trust boundaries, and authorization logic. The most dangerous vulnerabilities often aren’t single-line pattern violations, rather they’re systemic gaps where a validation function covers four of five cases, one endpoint is missing the authorization annotation its neighbors have, or encoding is applied in one context but not another.
Manual security reviews catch these issues, but they’re expensive, slow, and don’t scale to the pace of modern development. As code bases grow, teams are forced to choose between breadth and depth.
Full repository code review is built to close this gap. It gives your team an automated security researcher that reads and reasons about your entire repository, not just individual lines or file, and surfaces findings that pattern-matching tools miss.
How it works: Profile, search, triage, validate
Full repository code review operates in four stages that mirror how an experienced security engineer conducts an engagement.
Profile the application: The scanner begins by reading the entire repository and building a security model of the application including entry points, trust boundaries, data flows, authorization invariants, and the defenses already in place. This profiling step accounts for every source file, so coverage decisions are explicit rather than implicit. The result is a structured understanding of what the application does and where its attack surface lies.
Search for vulnerabilities: An orchestrator reads the security profile, reasons about the attack surface, and dispatches specialized agents to the highest-risk components. Each agent receives a scoped assignment with specific modules, threat context, and adversarial questions. Agents are free to follow imports and callers beyond their starting scope when a lead takes them there.
Triage and deduplicate: Candidate findings are deduplicated (same sink, same root cause) and low-confidence noise is filtered out before the validation phase.
Validate independently: For every candidate, an independent validator re-reads the source code and traces the full attack chain. The validator argues both sides: it looks for reasons the finding might not be a vulnerability (compensating controls, intentional design), and it looks for reasons it is one (alternative attack paths, edge cases). A finding is only rejected when the evidence against it is as strong as the evidence that promoted it. This process produces findings with structured Verified and Could not verifysections, so your team knows exactly what the scanner confirmed in the code and what depends on your deployment environment.
What makes this different
Full repository code review differs from traditional static analysis in two fundamental ways. It reasons about your application’s actual behavior rather than matching against known vulnerability patterns, and it presents findings with structured evidence that makes uncertainty explicit rather than hidden.
Context-aware reasoning, not pattern matching
Because the scanner builds a security model before searching for vulnerabilities, it reasons about the application’s actual behavior, not only surface-level code patterns.
Consider a real example: A stored procedure had a SQL injection vulnerability. A traditional SAST tool would flag the specific EXECUTE IMMEDIATE call. The scanner went deeper and it identified that the central validation function doesn’t block single quotes in any of its five regex profiles, listed all five profiles by name, explained why single quotes matter for the specific database engine, and noted that another stored procedure skips the validation function entirely. Instead of a point fix on one call site, the finding led to a comprehensive remediation of the systemic gap.
In another case, the scanner found an XSS vulnerability where a value was added to a field without HTML encoding. The same value was properly encoded with Encode.forHtml() in a different context within the same file. Pattern-matching tools miss this because the encoding function is present, but the vulnerability is the inconsistency, which requires understanding the application’s behavior across code paths.
Validated findings with transparent uncertainty
Every finding is structured for efficient developer triage:
Problem: What the code does wrong, with specific file and line references.
Impact: What an attacker gains, with details about deployment context.
Verified and could not verify:What the scanner confirmed directly in code versus what depends on your environment (network segmentation, runtime behavior).
Remediation: Concrete fix suggestions with specific code changes, not generic guidance.
Severity and confidence: Calibrated independently. Severity reflects the impact if the vulnerability is exploitable; confidence reflects how much of the attack chain was verified in code.
How full repository code review fits into your workflow
Full repository code review is designed to complement, not replace, your existing security tooling. Here’s how it fits into a modern development workflow:
Before security reviews:Run a full repository code review before scheduling a penetration test or security review. The review surfaces the obvious and semi-obvious issues so your security team can focus their limited time on the subtle, design-level questions that require human judgment.
When onboarding acquired or open source code:Full repository code review is especially valuable when your team inherits code through acquisitions or vendor dependencies, or from open source components you’re integrating. The scanner builds a security model from scratch, so it doesn’t need institutional knowledge of the codebase.
During architecture reviews:Because the scanner reasons about trust boundaries, data flows, and authorization invariants, its findings often surface architectural issues, not only implementation bugs. Review the scan results alongside your threat models to validate assumptions about how components interact.
Follow our Quickstart guide to set up and execute a full repo code review with AWS Security Agent.
Preview availability and pricing
Full repository code review is available today in preview at no additional charge for AWS Security Agent customers. During the preview, we welcome your feedback as we refine the experience. Use the built-in feedback mechanism in the Security Agent web application or reach out to your AWS account team.
The kernel’s dma-buf
subsystem provides a way for drivers to share memory buffers, usually
in order to support efficient device-to-device I/O. At the 2026 Linux Storage,
Filesystem, Memory Management, and BPF Summit, Pavel Begunkov, assisted
by Kanchan Joshi, led a joint session of the storage and memory-management
tracks to explore ways to make the use of dma-bufs more efficient yet, and
to make them available for read and write operations initiated by user
space.
Since 2013, Amazon Redshift has given the full power of a data warehouse in the cloud, at a fraction of the on-premises cost. Every architectural generation—from dense compute to Amazon RA3 instances, from provisioned to Amazon Redshift Serverless—has made each query cheaper, faster, and more efficient than the last.
For over a decade, as data volumes have grown and analytics requirements have evolved, organizations increasingly leverage both data warehouse tables for structured, frequently-accessed data and data lakes for cost-effective storage of diverse datasets. Add AI agents to the mix and they query your data warehouse at a scale that dwarfs typical human usage, leading to spiraling operational costs.
Amazon Redshift has doubled down on its core strengths to meet the demands of any workload — whether driven by humans or AI agents. For example, in March 2026, Amazon Redshift improved the performance of business intelligence (BI) dashboards and ETL workloads by speeding up new queries by up to 7 times. This significantly improves the response times of low-latency SQL queries, such as those used in near-real-time analytics applications, BI dashboards, ETL pipelines, and autonomous, goal-seeking AI agents.
Today, we’re announcing Amazon Redshift RG instances, a new instance family powered by AWS Graviton. RG instances deliver better performance, running data warehouse workloads up to 2.2x as fast as RA3 instances at 30% lower price per vCPU. Their integrated data lake query engine lets you run SQL analytics across your data warehouse and data lake from a single engine with performance up to 2.4x as fast as RA3 for Apache Iceberg and up to 1.5x as fast as RA3 for Apache Parquet. This blend of speed, cost efficiency, and an integrated data lake query engine makes Redshift RG instances well-suited to handle the high query volumes and low-latency requirements of today’s analytics and agentic AI workloads.
You can compare new RG instances and current RA3 instances:
Current RA3 Instance
Recommended RG instance
vCPU
Memory (GB)
Primary Use Case
ra3.xlplus
rg.xlarge
4
32
Small cluster departmental analytics
ra3.4xlarge
rg.4xlarge
12 → 16 (1.33:1)
96 GB → 128 GB (1.33:1)
Standard production workloads, medium data volumes
This approach reduces total analytics costs for customers running combined data warehouse and data lake workloads, while simplifying operations through a single system for querying both warehouse tables and Amazon Simple Storage Service (Amazon S3) data lakes. We recommend using the AWS Pricing Calculator with your specific workload patterns to estimate savings.
Getting started with Amazon Redshift RG instances You can launch new clusters or migrate existing clusters through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS API. The integrated data lake query engine is enabled by default.
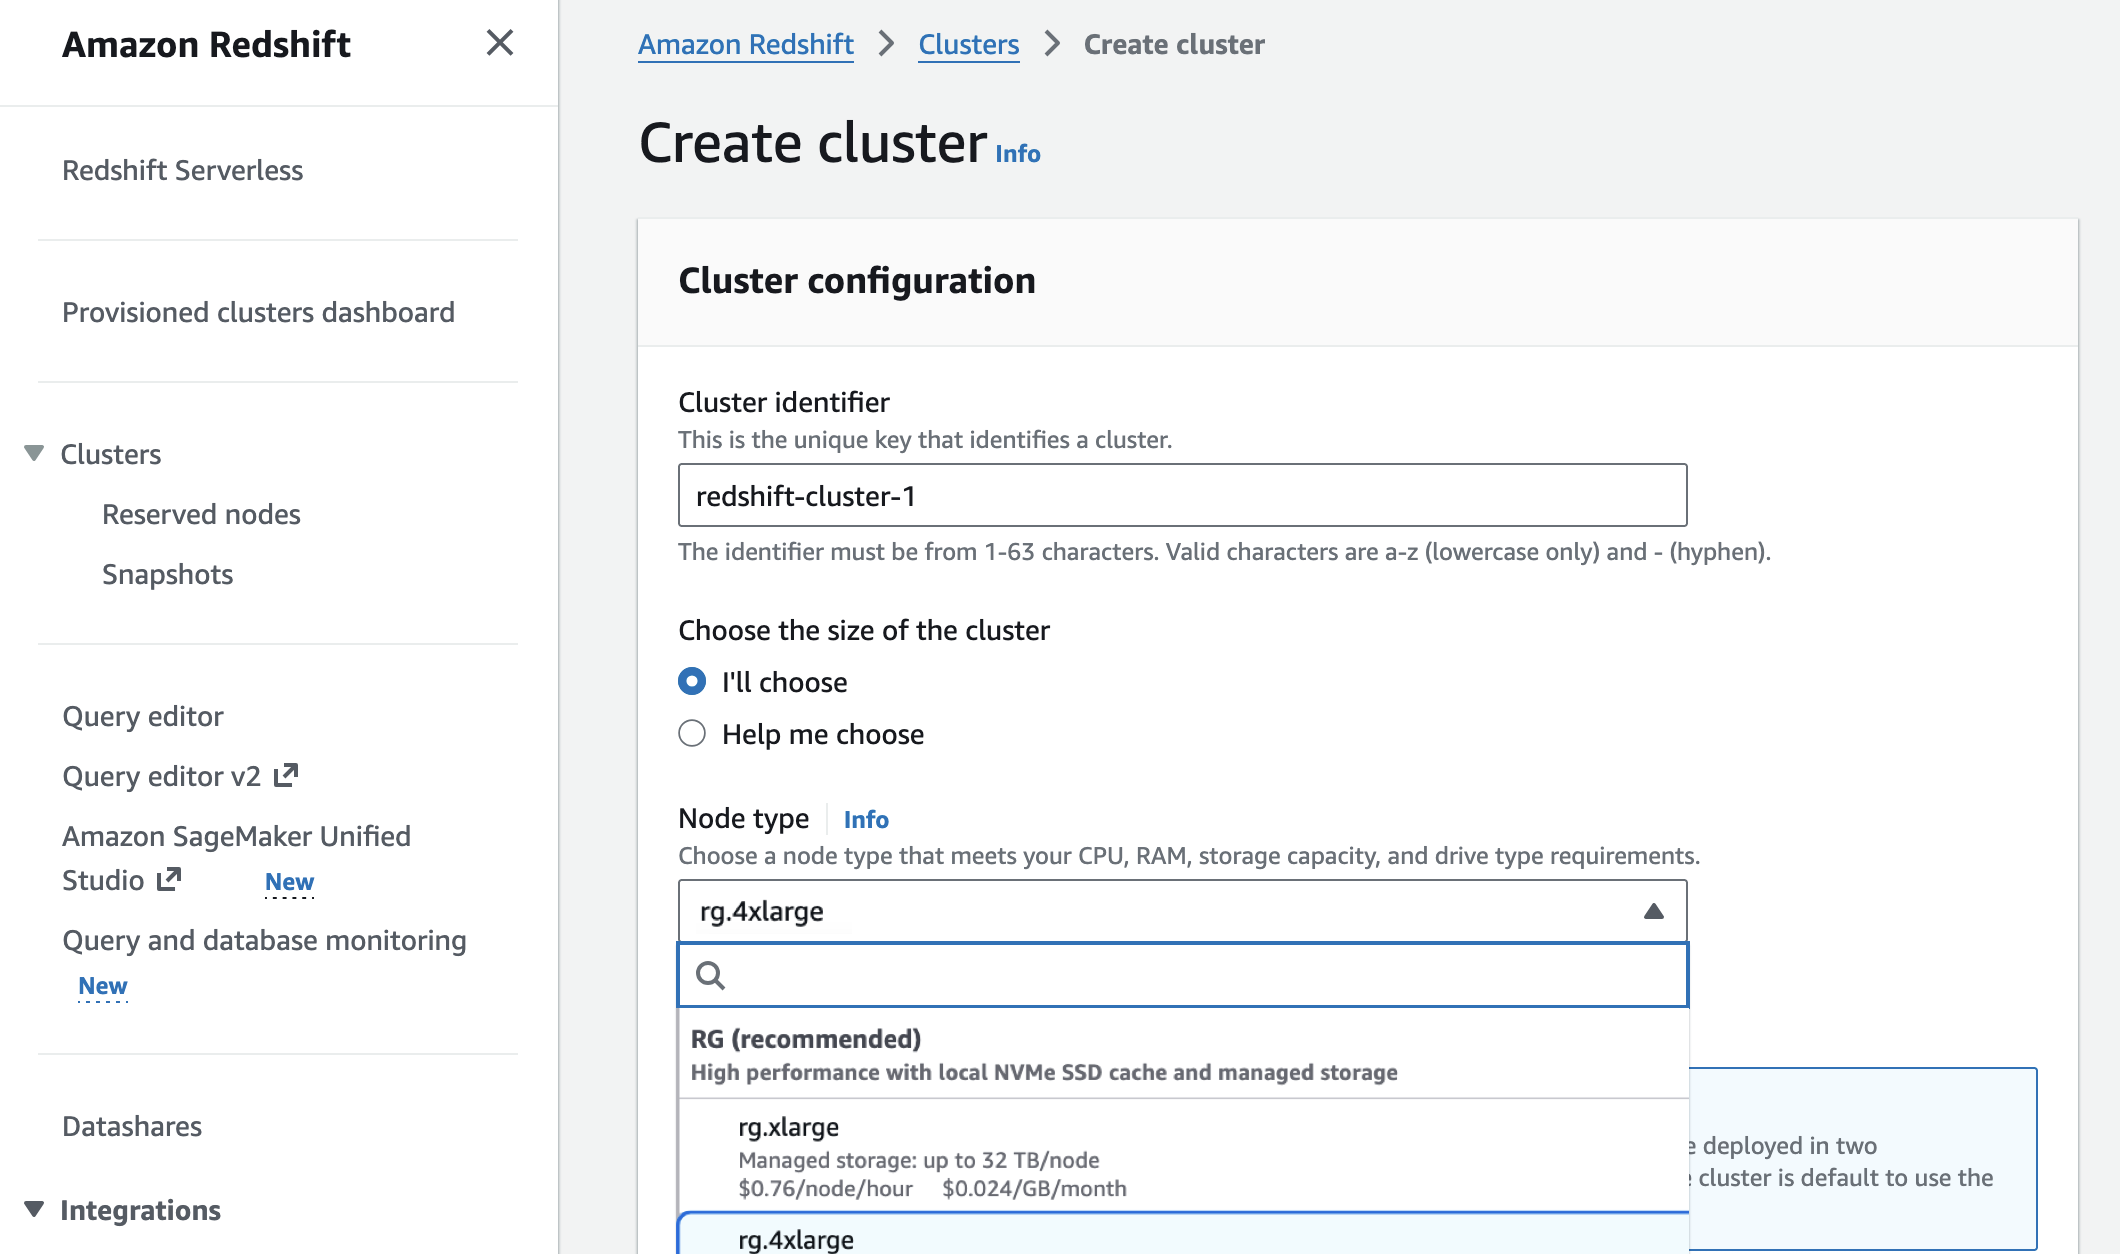
In the Amazon Redshift console, you can choose new RG instances when you create a cluster.
You can migrate previous-generation instances to RG instances with optimal paths based on your cluster configuration to estimate costs, validate compatibility, and automate execution.
Elastic Resize—in-place migration with 10-15 minutes downtime for compatible configurations
Snapshot and Restore—create a RG cluster from an RA3 snapshot. This is best for customers who want to make configuration changes during the migration
Your external tables, schemas, and query syntax—including existing Spectrum queries—remain unchanged. There is no need to recreate external tables or modify application code. To learn more, visit the Redshift Management Guide.
Amazon Redshift now executes data lake queries on cluster nodes—the same compute that processes data warehouse workloads. As a result, Amazon Redshift Spectrum is no longer required. Data lake queries stay within your VPC boundary, use existing IAM roles, and incur zero per-terabyte scanning charges. This removes the $5/TB Spectrum scanning fees that previously added to total Redshift costs.
Now available Amazon Redshift RG instances are now available in the following AWS Regions: US East (N. Virginia, Ohio), US West (N. California, Oregon), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Malaysia, Melbourne, Mumbai, Osaka, Seoul, Singapore, Sydney, Taiwan, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, Milan, London, Paris, Spain, Stockholm), Middle East (UAE), and South America (São Paulo). For Regional availability and a future roadmap, visit the AWS Capabilities by Region. For Redshift Provisioned, you can select On-Demand Instances with hourly billing and no commitments or choose Reserved Instances for cost savings. To learn more, visit the Amazon Redshift Pricing page.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.