Angine de poitrine, или от какво е направена музиката

Post Syndicated from Светла Енчева original https://www.toest.bg/angine-de-poitrine-ili-ot-kakvo-e-napravena-muzikata/
Angine de poitrine, или от какво е направена музиката

Минавала ли ви е през ума мисълта, че в музиката вече всичко е измислено? Че не може да се появи нещо, което не прилича на нищо досега? Че изкуственият интелект е способен да генерира произведения, не по-лоши от преобладаващата посредственост, и трудът на много музиканти може да стане излишен? Мечтаете ли си нещо да разтърси света на музиката, така че тя отново да започне да вдъхновява, да провокира, изобщо – да дава смисъл? Ако да, може би има надежда. Ако харесвате музика, която бяга от клишетата,

до вас вече може да е достигнала обсесията по канадското дуо Angine de poitrine.

В случай че не е – сега ще наваксаме.

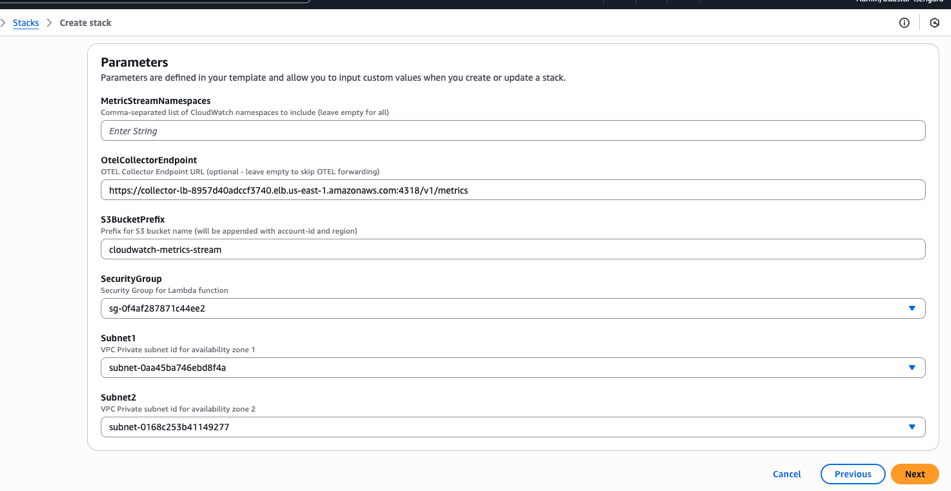
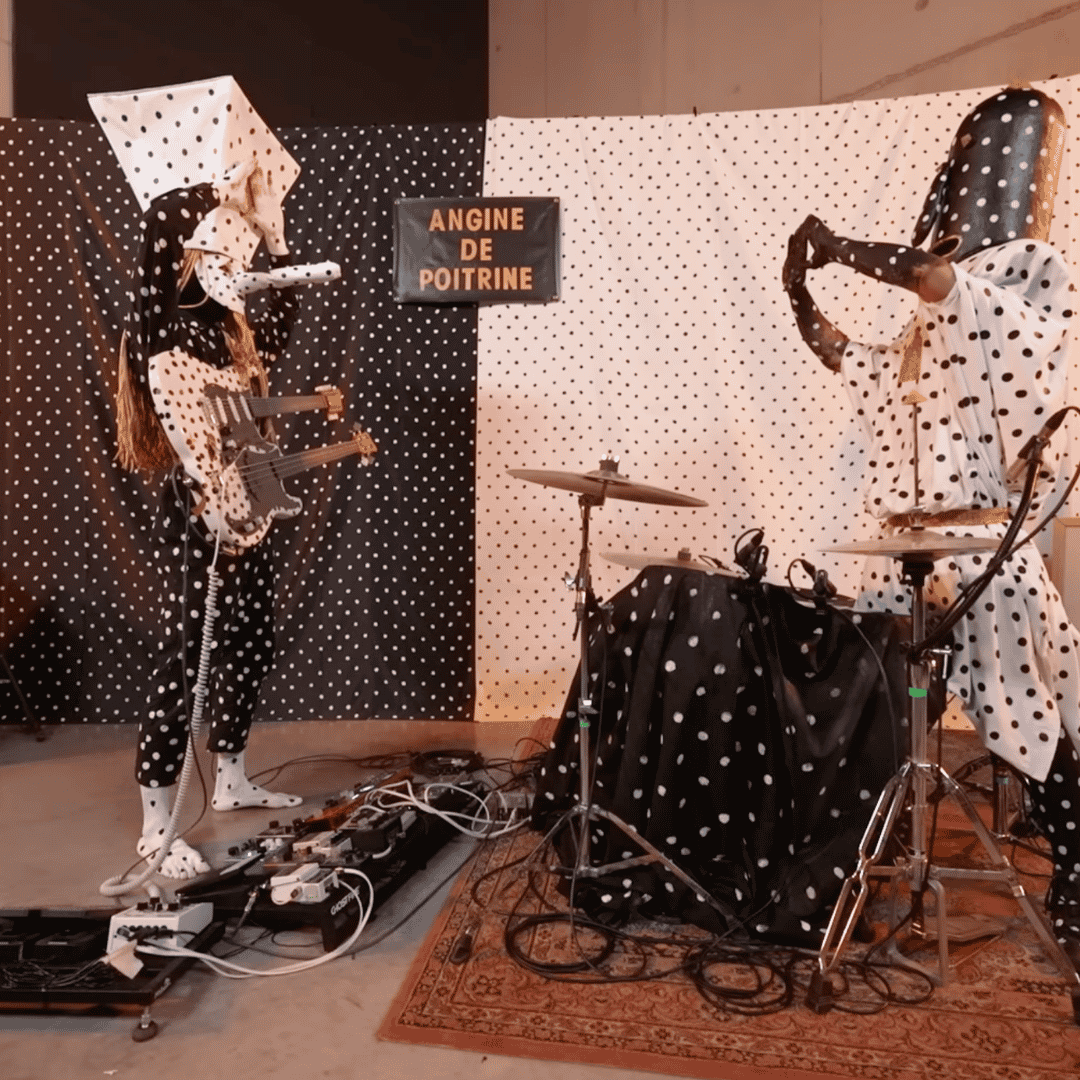
На френски името на групата означава ангина пекторис – медицинско състояние, по-известно като стенокардия или гръдна жаба. За анонимността на членовете на групата допринасят не само псевдонимите им (Khn de poitrine и Klek de poitrine), а и чудатите костюми на черни и бели точки, които скриват лицата им. Музикантите свирят на струнен инструмент с два грифа (китара и бас) и барабани. Khn използва босите си (но изрисувани на точки) стъпала, за да управлява ефекти като например лууп – записване и повтаряне на определени пасажи, върху които се свирят други.

Макар Angine de poitrine да са активни още от 2020 г., манията по тях е от март 2026 г., когато сиатълското радио KEXP качва в YouTube техен концерт, изнесен в Рен, Франция, през декември 2025 г.

Три месеца по-късно видеото е гледано (или поне отворено) над 14 млн. пъти, а YouTube изобилства от влогърски реакции на музиката на дуото. Екстравагантните канадци са почетени дори от Google – веднъж, когато търсех информация за Angine de poitrine, екранът на компютъра ми изненадващо се обсипа с черни точки.

Какво има между полутоновете?

Най-интересното в Angine de poitrine обаче не е външният им вид, нито анонимността им, а микротоналната им музика. За да разберем обаче какво е микротоналност, трябва да си припомним какво сме учили за тоновете.

Нека си представим клавиатурата на едно пиано. Ако започнем от произволен тон, например до, до същия тон в следващата октава (в случая – горното до) има общо 12 тона и полутона. Толкова е сборът на клавишите – седем бели плюс пет черни. Струнните и духовите инструменти също използват тази скала от 12 тона и полутона. Почти всички произведения в западната музикална традиция, които са ни известни, независимо от жанра им, са създадени върху нейната основа.

Ами ако някой изсвири тон, който е между до и най-близкия полутон, примерно, до диез? Обикновено това означава, че или инструментът не е настроен вярно, или човекът свири фалшиво.

Освен ако не става дума за микротонална музика.

Микротоновете са именно тоновете, които са между полутоновете. В микротоналната музика те не се възприемат като фалшиви, а имат право на съществуване. Микротоналностите не се свеждат до познатите ни 12 тона и полутона, а са изградени на други принципи.

На колко части, освен на две, може да се раздели един тон? Може да има 1/4 или 1/3 тон, но също и 1/17 например или каквато дроб ви хрумне. А може и разстоянието между два съседни тона да е различно от общоприетото. Защото тоновете са спектър – като цветовете. И преливането между тях е плавно. Затова и е практически невъзможно за човешкия глас, както и за голяма част от музикалните инструменти (освен може би издаващите дигитален звук) да постигнат абсолютно чисти тонове – те винаги се колебаят повече или по-малко около точния тон.

Angine de poitrine не са откривателите на микротоналността.

Тя съществува отдавна. Характерна е например за традиционната тайландска музика, в която се използва скала от седем тона на приблизително равни интервали, но различни от тези, с които сме свикнали.

Може да намерим микротонове на различни места по света, включително наблизо. Те са характерни и за турската музика, а не са съвсем чужди и на българския фолклор. Като се замислим, инструменти като гайдата и гъдулката, както и някои техники на народно пеене доста бягат от „правилните“ тонове. Което не е техен недостатък – напротив, в това им е чарът.

Впрочем микротонални инструменти се продават, и то не само фолклорни. При наличие на желание (и достатъчно средства) човек може да се снабди с микротонални китари, баскитари, струнни инструменти с два грифа като на Angine de poitrine и какво ли още не. Има дори микротонални пиана с подредби на клавишите от странни по-странни. Друг е въпросът, че всеки струнен инструмент, който няма прагчета, може да се използва за микротонална музика.

Откъде се вземат „правилните“ тонове?

Странното всъщност не е, че има микротонална музика. По-любопитният въпрос е: 

след като тоновете са спектър, защо огромната част от музиката е създадена върху системата от октави с 12 полутона на равни интервали един от друг?

Тази система, наречена равномерна темперация, е създадена в края на Ренесанса и зората на Новото време – публикувана е от Джовани Лафранко през 1533 г. Тя изразява общата нагласа на епохата всичко да се подчинява на ясни рационални правила.

След като равномерната темперация достига до Германия, в нея е въведен още по-строг ред. Йохан Себастиан Бах „постановява“ кои комбинации между тоновете са „добри“, тоест звучат хармонично, а не са в дисонанс. Това са мажорните и минорните тоналности (които стават основа на класическата музика, а и на огромна част от съвременната). Така, ако ползвате само белите клавиши на пианото и започнете от до, ще изсвирите гамата в до мажор, а ако започнете от ла – в ла минор. През 1722 г. Бах създава цикъла си „Добре темперирано пиано“, включващ прелюдии и фуги в мажор и минор, започващи от всеки от 12-те тона и полутона – общо 24 (12 мажорни и още толкова минорни). Двайсет и две години по-късно композира втора част на цикъла, също от 24 произведения.

Кое е вярното ла?

Освен че през Новото време тоновете са подредени в определени интервали и се определя кои са правилните хармонични комбинации между тях, как се решава какви да са самите тонове? Класическият помощник за настройване на музикални инструменти е камертонът, който по традиция издава тона ла. Честотата на тоновете се измерва в херцове, а ла на т.нар. първа октава е 440 херца.

Невинаги обаче е било така – стандартът от 440 херца е въведен чак в края на 30-те години на XX век, а е окончателно одобрен от Международната организация по стандартизация през 50-те. Ала и до днес не всички са съгласни, че 440 са правилните херцове. Битува и схващането, че по-доброто ла е с честота 432 херца (т.нар. строй на Верди – на името на композитора Джузепе Верди), тоест звучи малко по-ниско. Било защото за „виновник“ за 440-те херца се смята Гьобелс, било заради убеждението, че тонът, издаван на 432 херца, е по-естествен, по-топъл и по-близък до Вселената, било и поради двата аргумента. Съществуват и 432-херцови камертони, както и оркестри (включително български), свирещи в строя на Верди.

Но както хората не са знаели колко е часът, преди да имат часовници, така и не са можели да определят каква е честотата на един тон, преди да се появят уреди, с които да се измерва тя. Така че в миналото височината на един и същи тон е варирала чувствително. За ла-то има данни, че се е движило между 309 и 455,3 херца, което е сериозна разлика от близо шест полутона.

На бунт срещу тоналността

Микротоналната музика е преоткрита в края на XIX и началото на ХХ век. Не е сигурно кой е създателят на термините микротон и микротоналност. Въвежда ги или ирландската музикантка, теософка и поетеса Мод Маккарти, която е била повлияна от индийската музика, или мексиканският композитор Хулиан Карийо.

Този период е характерен с критика на модерността и на всичко, свързано с нея – научния прогрес, рационалността, капиталистическите отношения. Критиката е както от леви позиции (работниците са сведени до винтчета на машина), така и от дясноаристократични – капитализмът премахва старите йерархии заедно с ценностите, върху които се основават те. В заключението на книгата си „Протестантската музика и духът на капитализма“ германският социолог Макс Вебер говори за „стоманената клетка на бъдещето“.

Тази критика намира израз и в изкуството – чрез стилове като експресионизма, които си поставят за цел да разчупят класическите рационални и подредени форми. Възниква атоналната музика на композитори като Арнолд Шьонберг и Албан Берг, която стъпва на равномерната темперация от 12 тона и полутона, но отрича доминиращите мажорни и минорни тоналности. Преоткриването на микротоновете е част от същата тенденция на бунт срещу класическите правила.

Защо Angine de poitrine стават вайръл точно сега?

Има периоди, в които технологиите и креативността не са врагове. 70-те години на ХХ век например са такова време за музиката – в жанрове от диското до прогресиврока се създават звуци и ефекти, които не са съществували преди. Нови стилове възникват и в следващите десетилетия. В наши дни обаче технологиите като че ли се използват не толкова за да се създава нещо интересно, колкото за улеснение. Вече дори не се налага един музикант да умее да пее вярно – гласът може да бъде софтуерно коригиран даже в реално време, на концерт на живо. Коригираните, неестествено правилни гласове са вокалният еквивалент на разкрасяващите лицата и телата софтуерни филтри и на козметичната хирургия, произвеждаща хора без бръчки, но и без естествени мимики. Не че няма и талантливи изключения, но като че ли това е нормата.

Angine de poitrine не е първата микротонална група, нито единствената – такива са например и King Gizzard & The Lizard Wizard, The Mercure Tree и др. В сравнение с тях канадското дуо успява да направи впечатление и с екстравагантния си външен вид, и с използването на комплексни неравноделни ритми (на моменти напомнящи тези в българския фолклор), но и с това, че прави всичко по силите си да не прилича на нищо друго – и в музикално, и в сценично отношение, – доколкото това изобщо е възможно.

„Музиката е пространството между нотите“, казва Клод Дебюси.

Френският композитор има предвид тишината. Но нотите обозначават тонове, а между познатите ни тонове се крият и други – микротонове. Съжителстваме с тях, без дори да ги забележим.

Във време, в което бъдещето на музиката, както и на много други сфери изглежда застрашено от изкуствения интелект, Angine de poitrine ни връщат към въпроса от какво всъщност е направена музиката. Ако я разглобим до съставните ѝ части, ако видим какво има между тоновете, може би музиката има бъдеще. Може би ще успеем да я създадем по някакъв нов начин. Е, не точно аз, но по-музикални от мен представители на човечеството.
Beyond content: helping teachers feel ready to teach AI

Post Syndicated from Catarina Marques original https://www.raspberrypi.org/blog/beyond-content-helping-teachers-feel-ready-to-teach-ai/

We are working with partner organisations around the world to support teachers in building confidence with AI in the classroom through our Experience AI programme. In this guest post, Catarina Marques from our partner TUMO Portugal shares what the organisation is learning from delivering training to educators.

Whenever we run Experience AI training sessions, we keep coming back to the same thing: teachers are not lacking interest in AI, what they are lacking is time. Time to explore the technology and tools, time to talk about them with colleagues, and time to work out what they really mean for their classrooms.

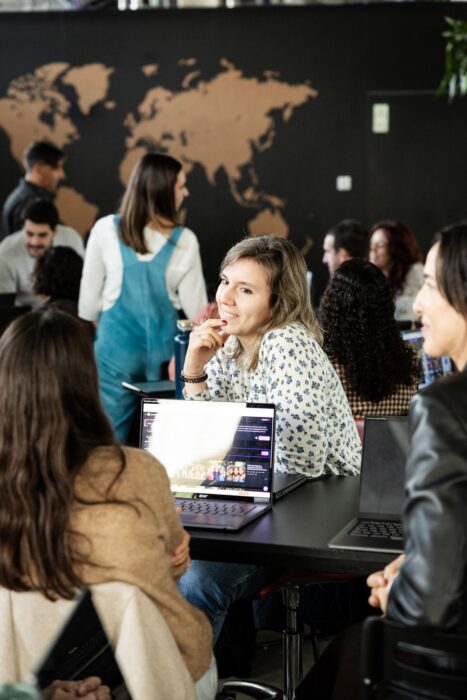
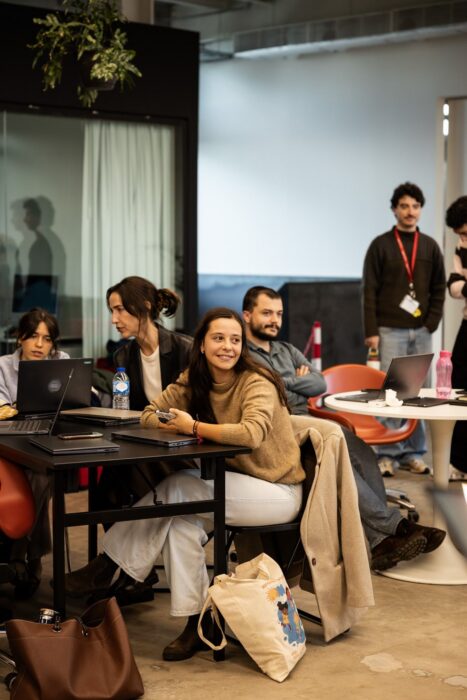
A group of people sat around a table with laptops.

And that matters, because AI is not something schools can just put off until later. It is already here. Students are hearing about it, using it, and forming opinions about it. Teachers are being asked to respond to it now, often while still trying to make sense of it themselves.

More than delivering content

The Experience AI teacher training is about more than educators to a set of resources. It is about helping them feel truly ready to take the Experience AI resources into the classroom and use them effectively with their students.

A group of people sat around a table with laptops.

What we see again and again is that teachers need space to stop and think. AI is moving quickly, and schools do not always have the time or support to keep pace. New tools are developed all the time. Expectations keep shifting. There is a lot of noise, and not always much room to pause and ask: what is actually useful here? What do we need to understand better?

In our experience, that is where real learning starts: not in rushing through information, but in discussing it, debating it, and testing ideas together.

Listening matters

One of the most valuable parts of these training sessions is the part where teachers start talking to each other.

They bring real questions into the room. Which AI tools can actually help with their work? How should they think about ethics? How do they talk about AI safety with students? How do they respond to something that may feel both useful and worrying at the same time?

A group of people sat around a table with laptops.

There is often confusion, and sometimes there is resistance too. That makes sense; this is still new territory for many schools. But there is also a real appetite to learn, especially because support in this area can still feel limited.

That is why listening is such an important part of our training. Teachers need space to reflect, compare experiences, and hear how others are approaching the same challenges. Very often, understanding grows through that process.

Play helps

Another thing we feel strongly about is that the training has to be engaging.

AI can feel intimidating. If the atmosphere is too heavy, it can be easy for people to step back from it. That is why the hands-on and playful side of Experience AI is so important. Team activities, discussion, and even a bit of healthy competition change the energy in the room. People get involved. They relax. They start exploring instead of worrying about getting everything right.

A group of people sat around a table with laptops.

That matters for teachers, and it matters for students too. When teachers experience this kind of learning for themselves, it becomes easier for them to imagine creating it in their own classrooms. Play is not separate from the learning here — it is part of what makes it stick.

Preparing schools for now

For us, this work feels urgent. Schools need the language, confidence, and literacy to engage with AI now, not in a few years’ time.

A group of people standing with laptops.

What teachers need most is not endless hype or more pressure. They need time to explore, time to discuss, time to understand, and time to build confidence. Experience AI has offered a way to begin that process.

If we want young people to engage critically and confidently with AI, we have to start by giving teachers the chance to do the same.

If you want to find out more about Experience AI, visit our website experience-ai.org

The post Beyond content: helping teachers feel ready to teach AI appeared first on Raspberry Pi Foundation.

How Dangerous Is Anthropic’s Mythos AI?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/05/how-dangerous-is-anthropics-mythos-ai.html

Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.

The announcement requires context—but it contained an essential truth.

While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.

At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have others parrot their claims?

Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.

Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.

But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.

Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.

But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.

Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.

Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.

Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.

As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.

The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.

AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.

This essay originally appeared in The Guardian.

Start small, dream big with Code Club: Become an Incubator Partner

Post Syndicated from Zoe Davidson original https://www.raspberrypi.org/blog/become-a-code-club-incubator-partner/

Imagine places for young people to not just learn to use technology but to understand it, shape it, and build with it. That’s what you can create by partnering with the Raspberry Pi Foundation on Code Club, the global movement of computing clubs where school-age young people develop the confidence to create with digital technologies.

We’re looking for organisations worldwide to join us as new Incubator Partners and bring Code Club to young people in their regions.

What is the Incubator programme about?

Through our non-funded 12-month global Incubator programme, we support a diverse network of organisations to establish and grow free Code Clubs in their communities. By combining your local knowledge and community connections with our tried and tested projects, training, and support, you can build something that lasts and grows.

As a partner, you’ll join a global network of organisations all working toward the same goal: giving young people access to free, inclusive, and inspiring opportunities to learn coding and digital making.

“Many of our partners are non-profit and volunteer-led, driven by a real commitment to their communities. It’s incredibly inspiring — and we’re excited to keep growing this global network of partners so even more young people can benefit.” – Sonja Bienert, Senior Global Partnerships Manager 

By joining, you’ll get partner-specific access to events like global meetups, online workshops, and Coolest Projects, as well as materials to support your fundraising. Your Code Clubs will be able to use our wide range of free, creative projects for young people, including activities about AI, and activities that support clubs with limited devices. And you’ll be able to build collaborations with other partners in the network.

Real stories from our partners

Across the world, our partners are already transforming lives.

Full Stack Vision Foundation, Aruba

In Aruba, Full Stack Vision Foundation has grown Code Club from a single library session into a thriving network of ten clubs:

“Giving young people the ability to make, create, and sustain technological solutions is what the Caribbean wants.” – Bruce Harms, Founder and President of Full Stack Vision Foundation

Three smiling young tech creators at a computer screen during a Code Club session in Aruba.

By adapting projects to reflect local culture — like reimagining a Scratch project around aloe vera instead of sugar — the team at Full Stack Vision ensures young people see themselves in what they’re creating.

Orientations Training Centre, Sudan & Egypt

In Sudan and Egypt, Orientations Training Centre has reached over 450 active members through a mix of in-person and online clubs:

“I learned that coding is not just about computers – it’s about solving problems and helping people.” – Yasmin, Code Club attendee

A young tech creator and a mentor look at a laptop screen during a Code Club session in Egypt.

“Start small but dream big. A Code Club can change lives – not just by teaching coding but by nurturing problem-solvers, innovators, and leaders for the future.” – Abdelmoneim Mohammed, CEO of Orientations Training Centre

Their work shows how getting creative with digital technology can unlock confidence, leadership, and ambition.

STEMUP Educational Foundation, Sri Lanka

In Sri Lanka, STEMUP Educational Foundation started with a single Code Club in a public library and has grown into a nationwide movement supported by more than 1,500 volunteers, reaching young people across both urban and rural communities.

Young people showcase their tech creations at Coolest Projects.

After attending a Coolest Projects event for young tech creators during the partner meetup we held in Malaysia, STEMUP brought the tech showcase to Sri Lanka for the first time in 2024, giving young people the chance to share their creations and connect with others. The event sparked huge excitement, with schools even organising transport so students could take part.

“That kind of energy… because they don’t have these opportunities to showcase what they have built, connect with like-minded people, connect with industry… I think that’s a really unique opportunity kids are having.” – Prabhath, founder of STEMUP Educational Foundation

A global movement powered by local leaders

Every partner brings something unique: local insight, cultural context, and a deep understanding of their community. Together, we’re building a global movement that is inclusive, creative, and full of possibility. 

“I feel part of something bigger — a worldwide movement where kids everywhere are learning to create with technology, not just consume it. Being a global partner means we can learn from what’s working in other countries, adapt those ideas to Bangladesh, and also contribute our own innovations back to the network. The global connection gives Code Club Bangladesh more recognition locally — it reassures schools, volunteers, and funders that we’re part of a trusted, established initiative.” – Code Club Bangladesh partner

Are you ready to get started?

You can register today to start your Code Club Incubator Partner application. If you’re passionate about empowering young people and ready to grow a network of computing clubs in your community, we’d love to hear from you.

Fill in the registration form to take the first step towards becoming an Incubator Partner:

We can’t wait to welcome the next group of Code Club Partners.

The post Start small, dream big with Code Club: Become an Incubator Partner appeared first on Raspberry Pi Foundation.

Няма такава дума в българския език!

Post Syndicated from original https://www.toest.bg/nyama-takava-duma-v-bulgarskiya-ezik/

Няма такава дума в българския език!

Чудно нещо е езикът – дава ни толкова възможности да изразяваме мисли, чувства, идеи, терзания, съгласия и противопоставяния, а ние, вместо да се възползваме пълноценно от тази свобода и да признаем, че всички разполагат с нея, понякога се впускаме в критика към казаното от събеседника ни. По-точно към формата, в която то е облечено.

Докъде всъщност се простира нашата толерантност към езиковия избор на другите? И кое подхранва синдрома на отрицанието му, който условно ще нарека „Няма такава дума в българския език!“?

Да тръгнем от един факт, който според мен трудно може да бъде оспорен:

повечето хора изобщо не правят разлика между български език и книжовен български език.

А тя е съществена. Книжовната форма е, образно казано, представителният, изисканият, дори идеалният вариант на българския. Точно тя – с много малки изключения – се изучава в училище през целия 12-годишен курс. Вероятно затова, когато чуват и употребяват понятието български език, хората разбират книжовната, тоест нормативната му форма, и напълно изключват териториалните диалекти и социолектите. Изключва се даже т.нар. книжовно-разговорна реч, която, както личи от нейното название, е част от книжовния език, макар и не съвсем.

Крайно време е да се разбере: и диалектните думи, и просторечието, и граматически грешните форми и конструкции, и вулгаризмите, ако щете, са част от българския език – онзи огромен речеви склад, от който всеки може да черпи в ежедневието си. Когато обаче общува публично, съвременният човек с прилична езикова култура следва да се ограничава в рамките на книжовната норма, даваща му впрочем пребогати изразни възможности.

Ето някои примери, при които съм срещала реакцията „Няма такава дума!“. Ще ги коментирам съвсем накратко.

Съпричинител. Доколкото ми е известно, този юридически термин е въведен през 2017 г. в Закона за движението по пътищата – чл. 119, ал. 5. А изобщо в съдебната практика се използва понятието съпричиняване, което, също както и съпричинител, ми изглежда достатъчно разбираемо. Ето, без да давам какъвто и да е контекст, и вие ще се сетите, че съпричинителят е човек, който заедно с друг е причинил нещо, и последиците от това нещо са лоши.

Варналия. Книжовната дума е варненец, а варналия е разговорна, но е широко употребявана и на мен лично тя ми звучи по-топло. За да сверя своето усещане, се обадих на мои приятели, които живеят в морския град. Според тях варналия е по-старият вариант и съответно в миналото се е срещал по-често. Пошегувахме се, че сега софиянци пишат речниците и определят кое е книжовно и кое – разговорно.

Тризнаци. Ще призная, че имам силна вътрешна съпротива срещу тази дума. Погледнато обективно обаче, за да означим три деца, родени при една бременност, трябва да използваме или тризнаци, или тройка близнаци. Е, тук влиза в сила законът за езиковата икономия, за който малцина знаят, но това не пречи той да си действа. Думата е включена в Речник на новите думи в българския език1 и е означена като разговорна.

Добропаметен. Много ми се иска това прилагателно име, което наистина се среща изключително рядко, да разшири употребата си, още повече че на злото трябва да се противостои по всякакъв начин, включително и в езика. Вярно, има злопаметни люде, но защо да се лишаваме от възможността някак да назоваваме и онези, които помнят стореното им добро? Струва си да се отбележи, че другите сложни прилагателни имена с втора част -паметен също са негативни: късопаметен и безпаметен2. Специално тези двете дават възможно най-синтезираното обяснение на изборното ни поведение.

Достъпвам. Толкова хейт, пардон, толкова злоба е отнесъл този безобиден неологизъм, че направо да го ожалиш. Иначе, ние сме против чуждиците, на оръжие, братя, да браним нашия мил роден език, налазен от нашествениците! Но дойде ли ред да измислим българско съответствие, някак много ни мързи. Съжалявам за грозната дума, но си е точно мързел, не е някаква изтънчена леност. Какво да ги правим сайтовете? Да ги аксесваме ли? Хайде по-добре да ги достъпваме. Какво му е на глагола? Всичко необходимо си има: представка, корен, наставка – все български. Значението му е ясно и без контекст. Но не, трябва да бърчим претенциозно нос и да връзваме кусур на всяко ново нещо в езика. Специално този глагол обещавам да го браня със зъби и нокти. Посочете ми едно разумно основание да не го използваме – и ще се откажа. (Разгорещих се, извинете, но и аз си имам пристрастия.)

Шофьорка, вицепремиерка, пулмоложка, колежка. Всички изброени думи са обединени от женския род и е естествено с тях да се назовават жени, заемащи дадена длъжност или упражняващи определена професия. Тенденцията за употреба на думи от мъжки род в тези случаи обаче е много силна и жените вече са шофьори, вицепремиери, пулмолози и колеги. Тъжното за мен е, че много от тях желаят да се представят с тези „мъжки“ думи. Водещият им мотив е, че „женските“ варианти звучат обидно и ги принизяват като личности.

Лидирам. Тук аз самата искам да възкликна: „Няма такава дума!“ Съществува в английския език във вида to lead. В българския разполагаме с богат набор от синоними. Няма нищо лошо и принизяващо някой да води, ръководи, насочва, направлява, оглавява, повежда… За някои обаче тези думи явно звучат простовато и са несъвместими със сложните политически процеси в нашата държава, а също така не съответстват на високото ниво на родните ни политици, които не просто водят нацията, а я лидират!

Последната дума е ярък пример за чуждица, която иска да се настани в българския език. Посочвам този факт най-вече за да обърна внимание на голямата динамика, която поначало е присъща на лексиката. В никоя друга езикова система промените не са толкова големи и бързи, колкото в речниковия състав. Това е един от основните фактори, които затрудняват не само обикновените хора, но и специалистите, когато се опитват да си отговорят на въпроса „Има ли я тази дума в българския език вече, или още я няма?“.

Критериите са много и разнородни.

Ще ни бъдат необходими три-четири статии, за да ги разясним, затова ще се спра накратко на някои от тях. Приема се, че след като дадена дума фигурира в речниците, тя е част от съответния език. За да попадне там обаче, трябва да отговаря на няколко условия, например да е показала

определена степен на устойчивост и да проявява тенденция за разширяване на употребата си…3

Съвременните технологии предоставят чудесни възможности за проследяване и количествено измерване на употребите и значително улесняват лингвистите в тяхната преценка. Вече имаме огромни корпуси с текстове на съвременен български език и ще се възползвам да ви препоръчам най-богатия от тях – CLASSLA. Тук е кажи-речи целият български интернет (без социалните мрежи, разбира се).

И така, необходимо е думата да има достатъчно много употреби, но се държи сметка също те да са в различни източници, в различни сфери, а не само в някоя строго професионална, да речем.

Освен това е нужно да е изминало някакво време, в течение на което даден неологизъм се употребява, въпреки че и това не е задължително. Когато настъпи епидемията от COVID-19, светкавично заехме локдаун от английски, а названието на болестта – ковид, се разпространяваше по-бързо и от самата зараза.

Нужно е също, ако лексемата е чужда, да е показала известна гъвкавост, тоест приспособимост към приемащия я език. Адаптацията се проявява в две посоки. Първата е способност за образуване на нови граматични форми, например пиар – пиарът/пиара, пиари, пиарите. Втората е словообразувателна активност – когато думата стане основа за образуване на нови думи в приемащия език: от пиар – пиарка, пиарски, пиарство, пиарствам.

За две от последните думи – пиар и пиарка, вече може да се твърди, че са признати на най-високо ниво, тъй като са включени в БЕРОН. Останалите фигурират в единия от цитираните речници на новите думи в българския език4. Ако някой много се страхува да ги употребява, ето, вече може да се опре на този факт.

Действително доста хора се въздържат да използват сравнително рядко срещани думи, особено пък по-нови.

По имейла съм получавала въпроси дали в българския език съществуват например: окултуряване, самокатастрофира, иновиращ, препотявам се, имейл (!), деволюция, татуировчик, приключенец, заскладяване, моктейл (безалкохолен коктейл), внимателност, антирекорд.

Много ми се иска да коментирам всички тези думи, но Word Count немилостиво отброява 8275 знака дотук и ме пришпорва да привършвам. Все пак ще кажа още едно-две неща, защото ги смятам за важни.

Какво да правим, ако дадена дума не е призната „официално“, тоест ако липсва в БЕРОН? Какво да правим, ако не я откриваме и в други речници на българския език? Съществува ли тя изобщо и може ли да я употребяваме? Според мен липсата на определена дума в речника не бива да е възпиращият фактор за нас. Никоя лексема не започва живота си в речник – започва я в живата реч, където тя прави първите си стъпки, после походката ѝ става все по-стабилна и смело и уверено тръгва по своя път. Все повече хора я забелязват, по някое време си казват: я, какво ново нещо се е появило, върши добра работа, защо пък да не го използвам и аз? По някое време и лексикографите регистрират неологизма, изследват употребите му, обсъждат го и ако отговаря на определените от тях критерии, го включват в съответния речник.

И така, първо думата се появява в живата реч, употребява се активно и едва тогава влиза в речниците.

Ако стоим и чакаме да видим нещо в речника, за да го използваме, никаква нова дума няма да бъде сътворена.

Естествено, не бива да бъдем и съвсем безкритични. Лично за мен е най-важно това, което казвам или пиша, да е разбираемо за хората и да е уместно в съответната речева среда.

Завършвайки, бих искала да споделя с вас един цитат от разказ на Хърбърт Уелс, на който попаднах, като търсех примери за статията.

Няма такава дума „виждам“ – рекъл слепецът…

Колкото повече разсъждавах над тези думи, толкова по-силно отекваше предупреждението в тях – че може да се хванем в капана на отрицанието поради ограничеността на собствените ни познания за света и чисто физическите си и ментални способности. Пожелавам и на себе си, и на вас по-рядко да попадаме в този капан и да не бъдем заслепявани за реалността, в това число и за езиковата реалност.

1 Е. Пернишка, Д. Благоева, С. Колковска. София: Наука и изкуство, 2010, с. 448.

2 Има още две такива думи – приснопаметен и достопаметен, но те са архаични.

3 Речник на новите думи в българския език. Д. Благоева, С. Колковска (ред). София: Наука и изкуство, с. 6.

4 Е. Пернишка, Д. Благоева, С. Колковска. Цит. съч., с. 323.

Езикът може да е вкусен и извън блюдото – онзи, българският език, на който говорим от малки и на който около 24 май се кълнем в обич. А той в същността си е средство за общуване и за да ни служи добре, непрекъснато се променя. Да го погледнем в неговата динамика и да се опитаме да разберем какво става и защо, кои са движещите механизми и как те са свързани с обществените процеси. И тъй като задачата не е лека, ще го правим постепенно – на порции.

[$] LWN.net Weekly Edition for May 14, 2026

Post Syndicated from corbet original https://lwn.net/Articles/1071535/

Inside this week’s LWN.net Weekly Edition:

  • Front: Fedora AI; Forgejo "carrot" disclosure; memory-management maintainership; huge THPs; mshare; 64KB base pages; DAMON; direct map.
  • Briefs: Dirty Frag; Fragnesia; Mythos and curl; killswitch; Debian reproducible builds; KDE investment; Quotes …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

Detecting and preventing crypto mining in your AWS environment

Post Syndicated from Jason Palmer original https://aws.amazon.com/blogs/security/detecting-and-preventing-crypto-mining-in-your-aws-environment/

This article guides you on how to use Amazon GuardDuty to identify and mitigate cryptocurrency mining threats in your Amazon Web Services (AWS) environment. You’ll learn about the specialized detection capabilities of GuardDuty and best practices to build a multi-layered defense strategy that protects your infrastructure costs and security posture.

Understanding the crypto mining challenge

Crypto mining in AWS environments represents a notable security challenge that extends beyond basic resource consumption.

When threat actors gain unauthorized access to cloud resources for mining operations, organizations face multiple consequences:

  • Cost increases that can range from hundreds to thousands of dollars.
  • Performance degradation that can affect legitimate workloads.
  • Potential additional security incidents that can lead to data exposure or ransomware deployment.

The complexity of crypto mining incidents continues to evolve, with unauthorized users employing advanced techniques to evade detection while maximizing resource use. Organizations often discover these intrusions only after they experience the financial effects or when resource exhaustion affects business operations.

When crypto mining indicates broader system vulnerabilities, additional concerns arise. Unauthorized users who gain access for mining purposes can install backdoors, expose sensitive data through compromised credentials, or create pathways for lateral movement within your AWS infrastructure.

Identifying signs of crypto mining activity

Organizations must remain vigilant for several key indicators of crypto mining activities. These indicators include connections to unknown IP addresses or the use of known mining pool ports, such as 3333. Sustained high CPU or GPU usage that doesn’t align with normal business operations can also signal mining activity. Unexpected network traffic patterns, particularly spikes to unfamiliar IP addresses, also warrant investigation.

Security teams must monitor for unfamiliar processes or applications that run without authorization on their resources.

How GuardDuty detects crypto mining

GuardDuty employs advanced detection methods specifically designed to identify crypto mining activities across your AWS environment. The service uses machine learning algorithms to analyze multiple data sources. These data sources are trained on global threat data gathered by AWS, anomaly detection that establishes behavioral baselines, and integrated threat intelligence from AWS Security and partners.

GuardDuty’s crypto mining detection capabilities include several specialized finding types:

GuardDuty monitors Amazon Virtual Private Cloud (Amazon VPC) Flow Logs for suspicious network patterns and analyzes DNS queries for mining-related domains. GuardDuty also scrutinizes AWS CloudTrail events for suspicious API calls and collects workload telemetry when you turn on Runtime Monitoring. This comprehensive approach allows for detection across Amazon EC2 instances, Amazon Elastic Container Service (Amazon ECS) clusters, Kubernetes environments, and standalone containers.

When you turn on the Runtime Monitoring feature, GuardDuty deploys lightweight agents that provide deeper visibility into runtime processes and system behavior, and enables findings such as CryptoCurrency:Runtime/BitcoinTool.B and Impact:Runtime/CryptoMinerExecuted. These findings detect crypto mining software that operates within your workloads. For containerized environments, Amazon Elastic Kubernetes Service (Amazon EKS) findings can indicate when unauthorized access is potentially used for crypto mining operations.

Building multilayered protection against crypto mining

Organizations typically find that crypto mining protection benefits from multiple security layers, with the detection capabilities provided by GuardDuty forming one component of a broader security strategy. Consider turning on GuardDuty across all AWS accounts and AWS Regions through AWS Organizations. Activated Runtime Monitoring and Amazon EKS protection features provide comprehensive coverage.

The following actions can enhance GuardDuty capabilities:

  • Configure Amazon CloudWatch to monitor resource use metrics and set alarms for unusual CPU, network, or GPU usage spikes that might indicate mining activity. Implement AWS Config rules to verify that security configurations are compliant. These checks make sure that security groups don’t allow broad internet access, and that IMDSv2 is enforced.
  • Deploy AWS Network Firewall to enable granular outbound filtering and allow necessary internet connectivity while blocking access to crypto mining infrastructure.
  • Deploy AWS Systems Manager to maintain visibility into instance configurations. Inventory, a capability of Systems Manager, tracks installed applications to detect mining software. Additionally, Run Command and State Manager—capabilities of Systems Manager—enforce security policies across your fleet.
  • Create automated remediation workflows that use Amazon EventBridge and Lambda to respond immediately when GuardDuty detects crypto mining activities.

Best practices for comprehensive protection

Access management and authentication

  • To strengthen your preventive measures, implement least privilege access with AWS Identity and Access Management (IAM). For software use cases, use IAM roles inside of AWS and IAM Roles Anywhere outside of AWS instead of long-lived access keys. For human identities, centralize user management through AWS IAM Identity Center with multi-factor authentication (MFA) features, in addition to attribute-based access control for fine-grained permissions. If you don’t use Identity Center, then turn on MFA for all IAM users, including those with administrative privileges, and require MFA for sensitive operations.
  • If you can’t eliminate the use of long-lived access keys, then implement regular access key rotation policies and apply least privilege access to all IAM policies. Regularly audit IAM permissions to identify and remove excessive privileges.

System maintenance and configuration

  • Use Patch Manager, a capability of Systems Manager, to implement automated patching and maintain current Amazon Machine Images (AMIs) for all deployed EC2 instances. Establish a regular patch cadence for all systems and test patches in non-production environments before you deploy a patch.
  • Implement strict ingress rules in security groups and allow only necessary traffic. Use egress filtering to prevent unauthorized outbound connections to mining pools. Regularly audit security group configurations to make sure that the configurations meet security requirements.

Data protection

  • Use AWS Key Management Service (AWS KMS)S) to turn on encryption for all data at rest, and implement TLS for data in transit. AWS KMS uses envelope encryption by default, and protects your data keys with master keys to provide enhanced security and performance. It’s a best practice to regularly rotate encryption keys.

Benefits of comprehensive crypto mining protection

Organizations that implement these comprehensive security measures can experience the following improvements in their security posture and operational efficiency:

  • Reduced detection time: Detection times for crypto mining activities decrease from days or weeks to minutes so that teams can rapidly contain issues before significant damage occurs.
  • Automated responses: Automated response workflows reduce manual intervention requirements so that security teams can focus on strategic initiatives.
  • Cost control: These measures identify and terminate unauthorized resource consumption and prevent unexpected billing increases.
  • Performance stability: Crypto mining processes no longer monopolize CPU, memory, and network resources so that your organization can maintain application performance.
  • Enhanced visibility: The monitoring approach helps identify crypto mining and other security threats that might go unnoticed.
  • Team confidence: Security teams gain confidence through continuous monitoring and automated alerts. Teams can be secure in knowing that crypto mining attempts are promptly detected and addressed.

The implementation of preventive controls reduces the potential for initial incidents. Regular patching and configuration management further strengthen your overall security posture.

Crypto mining approval on AWS

AWS requires written approval for crypto mining activities on AWS under AWS Service Terms (Section 1.25). This requirement helps protect both your resources and the broader AWS infrastructure.

Requesting approval

AWS Trust & Safety reviews requests to help prevent mining activities from negatively affecting service performance or security. When submitting your request, include the following information:

  • Describe your mining purpose and business case.
  • Outline your infrastructure planning and cost management approach.
  • Detail your security measures to prevent unauthorized access.
  • Provide emergency contacts for rapid communication, if issues arise.
  • Specify the number of instances and type of crypto mining.

What to expect after approval

Approved mining operations must follow specific guidelines to maintain good standing. AWS monitors approved mining activities to verify that the activities don’t generate abuse reports, effect service performance, or deviate from prescribed architecture and security practices.

Important considerations

Review the following information:

  • You can’t use AWS Credits and Free Tier resources for crypto mining activities.
  • It’s essential to continuously monitor your mining resources.
  • Based on changing infrastructure conditions, AWS can adjust approvals.

This approval process distinguishes legitimate mining operations from unauthorized activities that might indicate security compromises.

Conclusion

To protect AWS environments against crypto mining, AWS Trust & Safety recommends taking a comprehensive approach that combines advanced threat detection with proactive security measures. GuardDuty provides foundational detection capabilities that help to identify crypto mining activities, while complementary AWS services create a robust security ecosystem that protects your infrastructure and data.

Security is a shared responsibility. While AWS provides powerful tools and services designed to be highly secure, your organization’s implementation of security practices and controls determines your overall protection level. Regular review and updates of your security measures, as well as team training and awareness, help maintain an effective defense against crypto mining and other security threats in your AWS environment.

If you have feedback about this post, submit comments in the Comments section below.

Jason Palmer

Jason is a Senior Technical Account Manager (TAM) at AWS Enterprise Support, based in Seattle, Washington. With over 6 years at AWS, Jason combines deep technical expertise with a genuine passion for people — helping enterprise customers transform complex challenges into scalable cloud solutions.

Nadia Mahmood

Nadia is a Trust & Safety Customer Advisor at AWS, based in Virginia. Nadia works with enterprise customers on abuse reporting and compliance, handling escalated takedown requests and strategic partnerships to reduce abuse across AWS.

Contributors

Special thanks to James Ferguson, a Principal Solutions Architect and Jeffrey Bickford, a Security Engineering Manager, who made significant contributions to this post.

Introducing the updated AWS User Guide to Governance, Risk, and Compliance for Responsible AI Adoption

Post Syndicated from Krish De original https://aws.amazon.com/blogs/security/introducing-the-updated-aws-user-guide-to-governance-risk-and-compliance-for-responsible-ai-adoption/

The financial services industry (FSI) is using AI to transform how financial institutions serve their customers. AI solutions can help proactively manage portfolios, automatically refinance mortgages when rates decrease, and negotiate insurance premiums for customers.

However, this adoption brings new governance, risk, and compliance (GRC) considerations that organizations need to address. To help FSI customers navigate these challenges, AWS is excited to announce an updated AWS User Guide to Governance, Risk, and Compliance for Responsible AI Adoption within Financial Services Industries.

This comprehensive guide provides FSI customers practical considerations for responsible AI adoption across key dimensions including governance, risk management, compliance, data management, model management and AI agent management. It includes detailed AWS service capabilities that customers can use to address these considerations, such as Amazon Bedrock AgentCore, Amazon Bedrock Guardrails, Amazon Bedrock Agents, Amazon SageMaker Autopilot, and Amazon SageMaker Model Monitor.

The guide is available at the AWS Whitepaper portal and is complementary to other AWS resources such as the AWS Responsible Use of AI Guide, AWS Cloud Adoption Framework for AI, AWS Well-Architected Framework – Responsible AI Lens, AWS Well-Architected Framework – Generative AI Lens, and AWS Well-Architected Framework – Machine Learning Lens.

As the regulatory environment and leading practices continue to evolve, we will provide further updates on the AWS Security Blog and AWS Compliance Center. You can also reach out to your AWS account team for help finding the resources you need.

Resources

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Krish De

Krish De

Krish is a Principal FSI Governance, Risk, and Compliance (GRC) specialist. He works with AWS customers, their regulators, and AWS teams to safely accelerate customers’ AI and cloud adoption by providing prescriptive guidance on GRC. Krish has over 20 years of experience working in governance, risk, and technology across the financial services industry in Australia, New Zealand, and the United States.

Brenda Fong

Brenda Fong

Brenda is a senior FSI risk and compliance specialist. She works with AWS customers in banking, insurance, and capital markets within the ASEAN region to help them meet regulatory, governance, risk, and compliance expectations. Brenda has over 20 years of experience working in governance, risk, and technology across the financial services industry within Asia Pacific.

Stephen Martin

Steve is the Head of Financial Services Compliance and Security for EMEA and APAC. Steve Joined AWS after working for over 20 years in financial service in senior leadership roles with responsibility across ASIA, the Middle East, and Europe. At AWS, he supports customers as they use the scale, security, and agility of AWS to transform the industry.

Kelvin Leung

Kelvin Leung

Kelvin is the AWS FSI Security and Compliance Lead based in Hong Kong. He has 20 years of experience specializing in AI Governance, risk management and regulatory compliance within the financial services sector. Prior to joining AWS, Kelvin worked for a financial regulator where he was responsible for technology risk policy-making and IT regulatory examinations, with a particular focus on AI risk assessment and control frameworks.

PCI PIN and P2PE compliance packages for AWS Payment Cryptography are now available

Post Syndicated from Will Black original https://aws.amazon.com/blogs/security/pci-pin-and-p2pe-compliance-packages-for-aws-payment-cryptography-are-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of Payment Card Industry Personal Identification Number (PCI PIN) and PCI Point-to-Point Encryption (PCI P2PE) assessments for the AWS Payment Cryptography service. This assessment expands the AWS Payment Cryptography compliance portfolio, with AWS now validated as a component provider for Key Management (KMCP) and Key Loading (KLCP) in addition to the existing Decryption Management (DMCP) attestation, and extends PCI PIN and P2PE coverage to the South America (São Paulo) and Asia Pacific (Sydney) AWS Regions.

With Payment Cryptography, your payment processing applications can use payment hardware security modules (HSMs) that are PCI PIN Transaction Security (PTS) HSM certified and fully managed by AWS, with PCI PIN and P2PE-compliant key management. These attestations give you the flexibility to deploy your regulated workloads with reduced compliance overhead.

The PCI P2PE Decryption Component enables payment applications to use AWS to decrypt credit card transactions from payment terminals, and PCI PIN attestation is required for applications that process PIN-based debit transactions. The PCI P2PE Key Management and Key Loading Component attestations enable applications to use AWS for physical key exchange and to support key management use cases including key injection. To learn more about the new Physical Key Exchange feature, see the AWS What’s New announcement. With these capabilities, AWS Payment Cryptography enables customers to manage cryptographic keys in accordance with PCI standards and industry best practices, reducing the operational burden of maintaining compliant key management infrastructure.

The PCI PIN and PCI P2PE compliance packages for AWS Payment Cryptography includes the following reports:

  • PCI PIN Attestation of Compliance (AOC) – Demonstrates that AWS Payment Cryptography was successfully validated against the PCI PIN standard with zero findings
  • PCI PIN Responsibility Summary – Provides guidance to help AWS customers understand their responsibilities in developing and operating a highly secure environment for handling PIN-based transactions
  • PCI P2PE DMCP Attestation of Validation (AOV) – Demonstrates that AWS Payment Cryptography was successfully validated against the requirements for a PCI P2PE Decryption Management System with zero findings
  • PCI P2PE KMCP Attestation of Validation (AOV) – Demonstrates that AWS Payment Cryptography was successfully validated against the requirements for a PCI P2PE Key Management Component Provider with zero findings
  • PCI P2PE KLCP Attestation of Validation (AOV) – Demonstrates that AWS Payment Cryptography was successfully validated against the requirements for a PCI P2PE Key Loading Component Provider with zero findings
  • P2PE Component User’s Guide and Annual Component Report – Describes the AWS Payment Cryptography service assessment scope as a PCI P2PE Decryption Component, Key Loading Component, and Key Management Component and illustrates PCI P2PE compliance responsibilities for both the service and customers using the service for point-to-point encryption processing

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA). Customers can access the PCI PIN Attestation of Compliance (AOC) report, the PCI PIN Shared Responsibility Summary, the PCI P2PE Attestation of Validation, and P2PE Decryption Component User’s Guide and Annual Decryption Component Report through AWS Artifact.

To learn more about our PCI programs and other compliance and security programs, visit the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Will Black

Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

Tushar-Jain

Tushar Jain

Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 13 years of experience in information security and holds CISM, CCSK and CSXF certifications.

Jeff Cheung

Jeff is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelors degrees in Information Systems and Economics from SUNY Stony Brook, and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

Balaji Palanisamy

Balaji is the Industry Engagement Lead for AWS Payment Cryptography, helping financial institutions and payment companies modernize their cryptographic infrastructure. He combines pragmatic security strategy with hands-on solution architecture expertise, believing the best solutions balance technical and business needs. Always curious about security challenges, he stays current by reviewing emerging payment security standards.

[$] Friction in Fedora over AI developer desktop initiative

Post Syndicated from jzb original https://lwn.net/Articles/1071949/

A push by Red Hat employees to create a Fedora “AI Developer
Desktop” with support for out-of-tree kernel drivers and AI toolkits
has been met with objections from some long-time members of the Fedora
community. After more than a month of sometimes heated discussion, the
Fedora
Council
had voted
to approve the initiative; however, a last-minute change to vote against the
proposal by council member Justin Wheeler has (at least temporarily)
sent it back to the drawing board.

Securing client confidentiality at scale: Automated data discovery and governed analytics for legal workloads

Post Syndicated from Rohan Kamat original https://aws.amazon.com/blogs/big-data/securing-client-confidentiality-at-scale-automated-data-discovery-and-governed-analytics-for-legal-workloads/

Automating data security and analytics for legal documents presents a unique challenge when your legal team stores documents with strong access controls, organized by client and matter, encrypted at rest, and governed by well-defined policies. But what happens when you want to run analytics across those repositories? The typical path is extracting content into separate data pipelines or third-party tools, which fragments your governance model and introduces new risks. Law firms and corporate legal departments operate under distinct obligations that make data governance non-negotiable. Attorney-client privilege, work product doctrine, and professional conduct rules impose strict duties around how client information is handled, accessed, and disclosed. Governance failure in this context isn’t just a compliance gap, it can result in privilege waiver, disqualification from representation, or disciplinary action.

Legal professionals use ethical walls, also called information barriers, as structural safeguards that prevent the flow of confidential information between teams within a firm that represent adverse or potentially conflicting interests. Professional conduct rules mandate these barriers, and failure to maintain them can result in firm disqualification, malpractice liability, or regulatory sanctions.

Privilege boundaries are equally critical. Attorney-client privilege and work product protection apply only when you properly control access to the underlying material. If you expose privileged documents or metadata about their contents to unauthorized individuals, you risk losing your privilege protection. When organizations fail to maintain reasonable controls over privileged material, courts might find that they have waived their privilege. You should therefore actively manage your access governance, not only as a security concern but as a legal preservation requirement.When you extract content into separate analytics systems or grant broader access than your matter structures support, you create pressure on both protections. You gain visibility but lose confidence in your controls.

In this post, we show you a reference architecture that automates sensitive data discovery across legal document repositories on Amazon Web Services (AWS), demonstrate how to capture structured findings as a compliance dataset, and guide you through building a governed analytics workspace that maintains your security boundaries. You walk away with a practical model for building security and analytics into the same lifecycle, without moving documents outside their system of record.

Analytics shouldn’t weaken governance

Most legal organizations have invested heavily in securing their document repositories. You store documents in structured storage, organized by client and matter. You access controls map to matter boundaries (the organizational and access structures that separate one client engagement from another). You establish retention and hold policies.The difficulty starts when teams want to analyze what’s inside those repositories. Running analytics typically means copying content into a separate system, standing up a new data pipeline, or granting broader access than existing matter structures support. Each of these steps introduces governance gaps. Manual reporting fills some of the void, but it doesn’t scale and can’t provide continuous visibility. What’s missing is a model where security controls and analytics reinforce each other, where the act of discovering sensitive data also produces the dataset that you use for reporting, and where governance applies once and carries through every downstream operation.

Automation addresses this by combining continuous sensitive data discovery with governed analytics, built on discovery metadata rather than document copies. This automated approach delivers four key advantages:

  • No document movement. Your files stay in their system of record. Analytics runs against structured discovery metadata, not document content, so governance boundaries remain intact.
  • Continuous discovery instead of manual scanning. Automated classification identifies regulated and sensitive information on an ongoing basis, replacing periodic manual reviews with on demand visibility.
  • Unified governance. You define matter-aligned access policies once, and they carry through from document storage to findings analytics and compliance reporting.
  • Built-in audit readiness. A durable record of discovery findings and remediation actions accumulates automatically over time, giving you structured evidence for client reviews and regulatory inquiries.

Reference Architecture

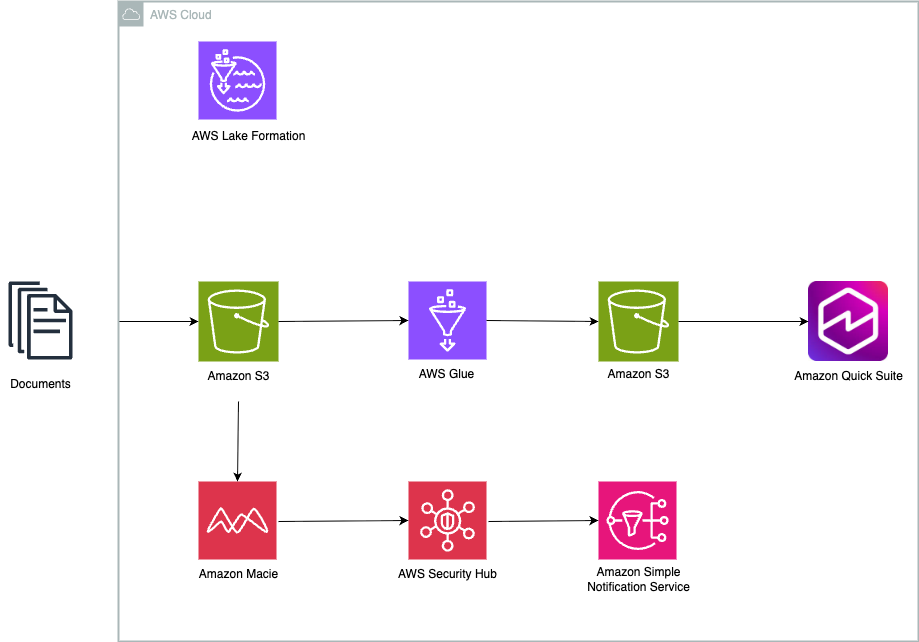
The following architecture shows how continuous discovery, governance, and compliance operations can work together without copying legal documents into analytics systems.

This reference architecture illustrates how law firms and corporate legal departments can automate sensitive data discovery and compliance analytics on AWS without moving documents outside their system of record

Architecture walkthrough

Store and protect documents in Amazon Simple Storage Service (Amazon S3)

Store your legal documents in Amazon S3, which serves as the system of record for document content. Align your buckets and prefixes to client and matter structures so that access controls map directly to matter boundaries. Where your retention or legal hold requirements demand it, apply S3 Object Lock to enforce immutability. You can encrypt your data using AWS Key Management Service (AWS KMS), which gives you centralized control over encryption keys and policies.

Discover and classify sensitive data with Amazon Macie

You will configure Amazon Macie to continuously analyze your document repositories. Macie identifies regulated information such as personally identifiable information (PII), financial data, and other sensitive content and produces structured findings that describe what Macie identified and where it exists. This provides ongoing visibility into data exposure without requiring document movement or manual scanning.

Catalog and govern findings with AWS Glue and AWS Lake Formation

You will use AWS Glue to catalog the findings dataset and maintain its schema so it stays query-ready. Apply AWS Lake Formation tag-based policies to govern access, aligning tags to client, matter, and confidentiality tier. This approach enforces ethical walls and least-privilege access consistently across analytics and reporting activities.

AI-powered chat agent using Amazon Quick Suite

You can create custom chat agents to tailor conversational interfaces for specific legal business needs. These agents can be configured with legal-specific knowledge bases, connected to relevant document repositories, and customized with instructions appropriate for legal workflows. You can use this chat agent to interact with your legal documents through natural language conversation for capabilities like:

  • E-Discovery:Search and analyze large volumes of legal documents to quickly find relevant information across your document repository.
  • Contract Analysis:Review contracts and automatically extract key terms, clauses, and obligations to streamline your contract review process.

The chat agent can help you navigate complex document sets through conversational queries, making legal research and document review more efficient and accessible.

Analyze and report with Amazon Quick Sight

You will use Amazon Quick as your compliance operations workspace. Quick provides a unified environment where your teams can query findings, generate dashboards, track remediation actions, and produce audit-ready reports. The agentic AI capabilities of Amazon Quick can autonomously build analyses, surface anomalies across matters, generate executive summaries for client reviews, and proactively recommend remediation priorities based on finding severity and trends. Combined with built-in data stories for automated narrative generation and pixel-perfect paginated reports for regulatory submissions, Quick reduces the time from discovery to action while keeping your teams within a governed interface aligned to matter-based permissions. Rather than switching between separate visualization, workflow, and reporting tools, your legal and compliance teams can review findings, manage response activities, and collaborate all within a single workspace that respects ethical walls and privilege boundaries.

Escalate high-severity findings

For high-severity findings that demand immediate attention, route alerts through AWS Security Hub or Amazon Simple Notification Service (Amazon SNS) to trigger escalation workflows. This connects visibility directly to action when your teams identify sensitive data risks.

Why this approach works for legal

Documents stay where they belong. Your files remain in Amazon S3, aligned to client and matter boundaries. No content moves into separate analytics pipelines.Ethical walls remain intact. Because analytics is built on discovery findings and not document copies, you can govern access to findings using the same matter-aligned controls that apply to documents. Compliance and security teams gain visibility without expanding document access.Discovery runs continuously, not periodically. Rather than scheduling quarterly or annual scans, you maintain a current view of sensitive data across your repositories.

Governance applies once and carries through. Lake Formation tag-based policies govern findings access at the catalog level. You define your matter and confidentiality mappings once, and they carry through to every dashboard, query, and report.Audit readiness is built in. Instead of assembling reports manually before a client review or regulatory inquiry, you maintain a historical record of discovery findings and remediation actions. You can demonstrate your posture over time with consistent, structured evidence.

Security and analytics reinforce each other. Your analytics capability is built on top of your security controls, not alongside them. Strengthening one strengthens the other.

Cost considerations

The primary cost drivers for this architecture include:

  • Amazon Macie: You pay based on the number of S3 buckets evaluated and the volume of data inspected for sensitive data discovery. Review Amazon Macie pricing for current rates.
  • Amazon S3: Storage costs for both your document repositories and the compliance intelligence bucket. Consider S3 lifecycle policies to tier older findings into lower-cost storage classes.
  • AWS Glue and AWS Lake Formation: Charges for crawlers and catalog storage. For most implementations, these costs are modest.
  • Amazon QuickSight: Per-user pricing based on the edition that you select (Standard or Enterprise). Enterprise edition supports row-level and column-level security, which aligns well with matter-based governance.
  • Amazon EventBridge, AWS Security Hub, and Amazon SNS: Charges based on event volume and notifications delivered. For findings-based workflows, these costs are generally low.

Use the AWS Pricing Calculator to estimate costs based on your repository size, user count, and discovery frequency.

Getting started

Start by identifying a representative set of document repositories in Amazon S3. We recommend that you start with two or three matters that span different practice areas and confidentiality tiers.

  1. Turn on Amazon Macie for those repositories and configure automated sensitive data discovery.
  2. Catalog the findings dataset with AWS Glue and apply Lake Formation tag-based access policies aligned to your matter structure.
  3. Build your first Amazon Quick Sight dashboard to visualize findings by matter, sensitivity type, and severity.
  4. Define escalation rules in AWS Security Hub or Amazon SNS for high-severity findings.

After you validate this workflow against your initial repositories, expand gradually. Add more repositories to Macie discovery. Refine your governance tags to reflect practice areas and confidentiality tiers. Extend your dashboards from basic posture visibility to trend analysis and remediation tracking.The goal isn’t to build a comprehensive analytics solution all at once. Start with a secure foundation where discovery findings, governance, and reporting operate together in a way that aligns with your legal workflows, and then expand from there.

Conclusion

You don’t have to choose between protecting client data and understanding it. By building analytics on top of governed discovery findings and using a unified compliance workspace, you gain visibility into your data posture without weakening confidentiality boundaries.This approach brings security, governance, and analytics together in a way that reflects how legal work is actually structured. It provides continuous visibility, supports audit readiness, and delivers insight without requiring documents to move outside their system of record.

Next steps

Review the Amazon Macie User Guide to understand sensitive data discovery configuration options and Amazon Quick Sight documentation to evaluate dashboard and row-level security capabilities.

Contact your AWS account team to discuss implementation support for legal and compliance workloads.


About the authors

Photo of Author - Rohan Kamat

Rohan Kamat

Rohan Kamat is a Solutions Architecture Leader within HCLS with extensive experience in cloud architecture, cybersecurity, Identity and Access Management, and enterprise networking. Rohan focuses on helping architects build both depth in cloud technologies and strength in executive communication, making sure they can confidently guide organizations through business and technical transformation. Outside of his professional work, Rohan enjoys time with his family, organizing community cricket events, and exploring fitness and wellness activities like pickleball and ping pong. He also enjoys planning travel experiences that bring people together and create lasting shared memories.

Photo of Author- Miguel Lopez Luis

Miguel Lopez Luis

Miguel Lopez Luis is an AWS Solutions Architect who works with small and medium businesses across the United States. He graduated with a Bachelor’s degree in Cybersecurity from Bellevue University in Nebraska and is a member of the Omega Nu Lambda Honor Society. Leveraging his extensive expertise in business management, Miguel is passionate about planning strategic initiatives, leading cross-functional teams, and mentoring others. In his personal time, he enjoys activities that involve travel, sports, and cooking.

Photo of Author - Pranali Khose

Pranali Khose

Pranali Khose is an AWS Solutions Architect based in Seattle. She works directly with small and medium business (SMB) customers across the United States, to design and implement cloud solutions that address their unique business challenges and accelerate digital transformation. Pranali holds a Master of Science in Computer Science from the University of Texas at Arlington.

Streaming CloudWatch metrics to VPC-based OpenTelemetry collectors using Lambda

Post Syndicated from Behzad Dastur original https://aws.amazon.com/blogs/architecture/streaming-cloudwatch-metrics-to-vpc-based-opentelemetry-collectors-using-lambda/

Organizations are increasingly drawn to open-source observability frameworks like OpenTelemetry. They seek to reduce costs associated with third-party licensing and avoid vendor lock-in. Combining OpenTelemetry collectors with Amazon CloudWatch Metric Streams helps enterprises pursue their observability goals while eliminating third-party licensing fees and achieving sub-minute latency for real-time alerting. CloudWatch Metric Streams offer built-in support for publishing to OpenTelemetry endpoints, but organizations that self-host OpenTelemetry collectors within their VPC need a way to bridge the gap between metric streams and internal HTTP endpoints.

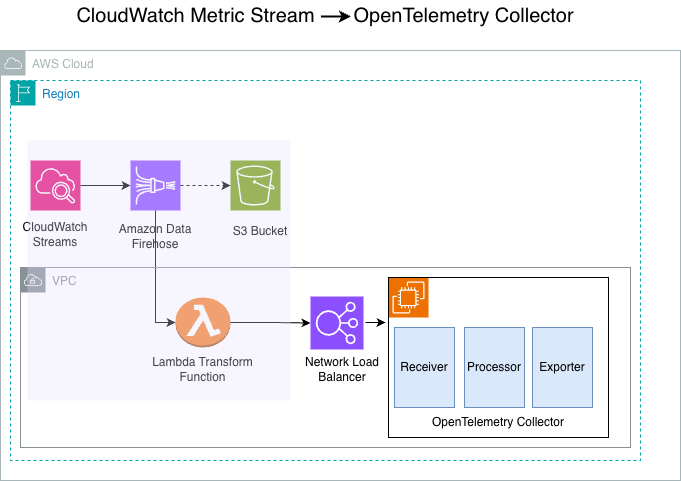
In this post, we demonstrate an approach we used to address this challenge for a customer by implementing an AWS Lambda transformation function that streams Amazon CloudWatch metrics directly to internal OpenTelemetry collectors running within a VPC.

Common observability challenges overcome with OpenTelemetry

Traditional monitoring becomes expensive and difficult to manage as cloud infrastructure grows. Many enterprises face a choice between expensive third-party observability solutions and the technical limitations of legacy metric collection methods. When organizations adopt cloud-native solutions and transition from monolithic applications to microservices, metric collection for observability becomes even more important.

Many operations and development teams face the challenge of building monitoring solutions that include tools and frameworks from different vendors and open-source projects, with different specifications and protocols, resulting in complex and fragmented landscape that’s difficult to maintain. OpenTelemetry is becoming the primary way to implement observability for many organizations. OpenTelemetry is an open-source framework for collecting traces, metrics, and logs. It works with any observability platform. Amazon CloudWatch, the AWS monitoring service, provides an open source distribution of OpenTelemetry called AWS Distro for OpenTelemetry to help you get started with OpenTelemetry. OpenTelemetry gained industry adoption primarily because of the standardization it provides enterprises through the following benefits:

  • Single set of APIs and libraries to capture distributed traces and metrics that can be sent to any observability platform
  • Future-proofing by avoiding vendor lock-in and enabling flexibility in choosing observability backends
  • Broad vendor support because it is open sourced and natively supported by numerous vendors

Pull vs push-based monitoring architecture

In a pull model like Prometheus, the monitoring server periodically scrapes metrics from endpoints. Although this model provides more control over query frequency, it runs into challenges at scale. Our customer’s current monitoring solution with Prometheus and Amazon CloudWatch exporter using a pull-based approach resulted in higher API throttling. This caused metric loss and created gaps in observability data for business-critical systems. The frequent polling approach in this model also resulted in higher costs from API calls. This polling solution did not satisfy their requirement of sub-minute latency for real-time alerting.

To overcome these challenges, we recommend a push–based architecture. The push-based solution, using CloudWatch Metric Streams to push metrics to OpenTelemetry collector, addresses these challenges by reducing frequent polling and API calls, enabling near real-time data transmission, and potentially eliminating licensing costs from using third-party solutions. Using OpenTelemetry’s push-based model, enterprise applications can send telemetry (traces, metrics, logs) to a collector or backend that offers significant benefits for real-time observability, such as:

  • Event-driven architecture: The push approach transmits data in near real-time by triggering collection based on events, not periodic polling. This is particularly valuable when using OpenTelemetry collectors that can push metrics to multiple services like Amazon Managed Prometheus (AMP), AWS X-Ray, Amazon CloudWatch, and Amazon OpenSearch.
  • Cost efficiency: Push models are significantly more cost-effective than pull models. Instead of continuously scanning large datasets, systems only process and transmit data when relevant events occur, reducing both computational overhead and data transfer costs.
  • Scalability: The OpenTelemetry collector serves as a central hub that can scale horizontally to handle varying traffic volumes while providing at-least-once delivery guarantees with automatic retry mechanisms.
  • No licensing costs: The Apache 2.0 license is free and royalty-free, meaning you can use, modify, and distribute OpenTelemetry without any licensing fees or ongoing costs.
  • No vendor lock-in: The permissive nature of Apache 2.0 means you’re not tied to any specific vendor’s implementation or support model. You can modify the code, switch between different OpenTelemetry distributions (like AWS Distro for OpenTelemetry), or even fork the project if needed.

How we built a scalable push-based observability solution

Our solution involves configuring an Amazon Data Firehose stream, that receives Amazon CloudWatch metrics and sends them to an OpenTelemetry collector within our customer’s VPC. Because of their strict data privacy requirements, our customer required the metric data and the OpenTelemetry collector to be within their VPC. A Network Load Balancer (NLB) serves as the internal endpoint to receive metric streams. Amazon Data Firehose natively supports data delivery to HTTP endpoints, but these endpoints must be public – they cannot be private endpoints inside a VPC. To overcome this limitation, we use the Amazon Data Firehose transform configuration, that invokes a Lambda function synchronously, which then securely pushes the metrics through the NLB endpoint to the collector running within the VPC. With this solution our customer could then aggregate and display all their metrics from AWS, other accounts, and on-prem systems in a single pane of glass dashboard.

The following diagram shows the architectural blocks of the solution:

Figure 1: Reference architecture for the Amazon CloudWatch Streams to OpenTelemetry collector solution

The solution consists of 4 main components – CloudWatch Metric Streams, Amazon Data Firehose, AWS Lambda, and the OpenTelemetry collector.

  1. CloudWatch metric streams: CloudWatch Metric streams enables you to stream CloudWatch metrics in near real-time, with minimal setup and without writing code. In this architecture, CloudWatch streams metrics to our configured Amazon Data Firehose stream. With CloudWatch Metric Streams, you can stream metrics in OpenTelemetry 0.7, 1.0, and JSON formats. This architecture uses JSON format as the stream output.
  2. Amazon Data Firehose stream: A fully managed service that reliably captures, transforms, and delivers real-time streaming data to the customer’s internal endpoint.
  3. Lambda transform function: Amazon Data Firehose supports Lambda-based data transformation that allows you to preprocess, enrich, filter, or modify streaming data before delivery to destinations. Because Firehose cannot deliver metrics directly to private VPC endpoints, we use Firehose’s data transformation feature with Lambda to bridge this gap and deliver metrics to internal endpoints. Amazon Data Firehose buffers incoming data before synchronously invoking the Lambda function that streams the metrics to the internal HTTP endpoint.
  4. The OpenTelemetry collector: In this solution, the OpenTelemetry collector runs as a container in an EC2 instance. The collector is a central hub that receives, processes, and forwards telemetry data (metrics, traces, and logs) from various sources to multiple destinations in a vendor-neutral way. The OpenTelemetry collector operates through three primary components that work together in a processing flow: Receivers accept data in specified formats (like Prometheus or OpenTelemetry Protocol (OTLP)) and translate it into OpenTelemetry’s internal format; Processors manipulate and enrich the data as it flows through (filtering unnecessary data, batching for performance, transforming to mask sensitive information, or adding metadata like Kubernetes attributes); and Exporters send the processed data to destination backends such as Grafana Cloud, AWS X-Ray, Lightstep or Honeycomb.

The reference architecture also shows the following components:

  1. Amazon Simple Storage Service (Amazon S3) bucket: The S3 bucket is a redundant destination for the CloudWatch Streams. Because our Lambda transform function sends the data directly to OpenTelemetry endpoint, no metrics are sent to the S3 destination, and it does not incur any cost.
  2. Network Load Balancer: This NLB operates at the transport layer of the Open Systems Interconnection (OSI) model. In this architecture, the NLB distributes TCP traffic to the OpenTelemetry collectors running on EC2 Instances in the internal subnet within the VPC.
  3. Amazon Elastic Compute Cloud (Amazon EC2) instance: In this architecture, we run the OpenTelemetry collector on the EC2 instances. The instances run in the private subnet within our VPC.

The following sections detail the steps for deploying this solution in your own AWS environment. You can deploy this solution using either AWS CloudFormation or the AWS Command Line Interface (AWS CLI). Deployment time and complexity will vary based on your familiarity with these AWS services.

Implementation details

Prerequisites:

Before deploying this solution, verify that you have the following:

  • An AWS account with permissions to create CloudWatch Metric Streams, Amazon Data Firehose, Lambda, and EC2 resources
  • AWS CLI v2 installed and configured.
  • AWS Serverless Application Model (AWS SAM) CLI installed.
  • A VPC with at least two subnets configured in different Availability Zones and security groups to allow necessary inbound and outbound traffic.

We can implement this architecture in two ways: deploying with AWS CloudFormation or deploying with the AWS CLI.

Option 1: Deploying with AWS CloudFormation

This walkthrough creates a CloudFormation stack, that deploys an Amazon Data Firehose stream, Amazon CloudWatch stream, S3 bucket, Lambda function for data transformation.

Access the CloudFormation template by cloning the git repository.

Step 1 – Package the Lambda artifacts for the CloudFormation template.

This step creates the cf-packaged-file.yaml file and publishes the Lambda Layer code packaged to the specified S3 bucket cf-stage-bucket-203918862653:

~> pwd
   sample-cloudwatch-metrics-stream-otel-transformer/cloudformation 
~> ./setup_layer.sh 
~>
~> aws cloudformation package \
    —template-file ./cloudformation-template.yaml \
    —s3-bucket cf-stage-bucket-xxxxx \
    —output-template-file cf-packaged-file.yaml

   Uploading to 9813804ccc99d538f6d4ef06c4857bab 223 / 223.0 (100.00%)
   Successfully packaged artifacts and wrote output template to file cf-packaged-file.yaml.
   Execute the following command to deploy the packaged template
  aws cloudformation deploy —template-file ~/code/sample-cwmetrics-   sep25/sample-cloudwatch-metrics-stream-otel-transformer/cloudformation/cf-packaged-file.yaml —stack-name <YOUR STACK NAME>

Step 2 – Create CloudFormation stack using the console.

  1. Sign in as an administrator to the AWS Management Console and use the navigation bar to select your preferred AWS Region for deployment.
  2. Navigate to the CloudFormation dashboard to create stack.
  3. Choose ‘Create Stack’ and choose “Choose an existing template”. Upload the template file and choose the cf-packaged-file.yaml created in the first step.

  1. Configure the key parameters.

  1. Acknowledge the Capabilities to allow CloudFormation to create the necessary LambdaExecutionRole IAM role with the required permissions.

  1. Finally, review and choose ‘Next’ to create the CloudFormation stack.

Option 2: Deploying with AWS Command Line Interface

Alternatively, you can run the following steps from a terminal using the AWS CLI to package and create your CloudFormation stack.

Access the CloudFormation template by cloning the git repository.

Step 1 – Package the Lambda artifacts for the CloudFormation template.

This step creates the cf-packaged-file.yaml file and publishes the Lambda Layer code packaged to the specified S3 bucket cf-stage-bucket-203918862653.

~> pwd
   sample-cloudwatch-metrics-stream-otel-transformer/cloudformation 
~> ./setup_layer.sh 
~>
~> aws cloudformation package \
    —template-file ./cloudformation-template.yaml \
    —s3-bucket cf-stage-bucket-xxxxxxxxxx \
    —output-template-file cf-packaged-file.yaml

   Uploading to 9813804ccc99d538f6d4ef06c4857bab 223 / 223.0 (100.00%)
   Successfully packaged artifacts and wrote output template to file cf-packaged-file.yaml.
   Execute the following command to deploy the packaged template
  aws cloudformation deploy —template-file ~/code/sample-cwmetrics-   sep25/sample-cloudwatch-metrics-stream-otel-transformer/cloudformation/cf-packaged-file.yaml —stack-name <YOUR STACK NAME>

Step 2 – Create stack using AWS Command Line Interface.

Create a parameters.json file as follows:

%~> cat parameters.json 
[
  {
    "ParameterKey": "Subnet1",
    "ParameterValue": "subnet-xxxxxxxxxx"
  },
  {
    "ParameterKey": "Subnet2",
    "ParameterValue": "subnet-yyyyyyyyyy"
  },
  {
    "ParameterKey": "SecurityGroup",
    "ParameterValue": "sg-xxxxxxxxxx"
  },
  {
    "ParameterKey": "OtelCollectorEndpoint",
    "ParameterValue": "http://your-otel-endpoint:4318/v1/metrics"
  },
  {
    "ParameterKey": "MetricStreamNamespaces",
    "ParameterValue": ""
  },
  {
    "ParameterKey": "S3BucketPrefix",
    "ParameterValue": "cloudwatch-metrics-stream"
  }
]

Run the CloudFormation create-stack CLI as follows:

~> aws cloudformation create-stack \
     --stack-name cw-metrics-demo \
     --template-body "file://cf-packaged-file.yaml" \
     --parameters file://parameters.json \
     --capabilities CAPABILITY_NAMED_IAM \
     --region us-east-1 --profile dev

After you deploy the infrastructure stack, CloudWatch Metric Streams initiates the flow by streaming near real-time metrics from customer applications. Amazon Data Firehose asynchronously invokes the Lambda transform function that sends metrics directly to the OpenTelemetry collector endpoint. You must then configure these collectors to apply additional processing, such as filtering, batching, and enrichment. The collectors forward metrics to one or more observability backends, such as Honeycomb, Jaeger, Grafana Cloud, or other dashboards.

Clean up

To avoid incurring unnecessary charges after testing the proof of concept (POC), clean up the resources. You can do so by deleting the CloudFormation stack to remove all deployed resources.

Option 1: Using the console:

  • Sign in as an administrator to the AWS Management Console and use the navigation bar to select your preferred AWS Region for deployment.
  • Navigate to the CloudFormation dashboard to create stack.
  • Select the ‘cw-metrics-demo’ stack and choose “Delete”.

Option 2: Using AWS CLI:

aws cloudformation delete-stack \ --stack-name cw-metrics-demo \ --region us-east-1 --profile dev

Conclusion

In this post, we showed how moving from third-party observability tools to CloudWatch Metric Streams with OpenTelemetry can reduce costs and improve performance. The solution we implemented combines AWS streaming with the OpenTelemetry standard to create a flexible and scalable monitoring solution that can adapt to changing requirements while maintaining operational excellence. If you face similar challenges with your observability solution, this approach offers a proven path to reduce costs, improve performance, and maintain control over your monitoring data.


About the authors

The collective thoughts of the interwebz