Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=h5uNqPwzN-I
What Is Preemptive MDR? A Guide For Security Leaders
Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/dr-what-is-preemptive-mdr-security-leaders-guide
When an MDR provider contains a compromised endpoint, your team needs to know whether the weakness that enabled the attack exists elsewhere and who is responsible for addressing it. Without that follow-through, the immediate incident may be resolved while another attacker still has a way in.
Preemptive managed detection and response (MDR) is Rapid7’s approach to connecting exposure context, threat intelligence, AI-assisted investigation, and human expertise. It supports proactive cybersecurity by helping teams prioritize weaknesses before exploitation, investigate threats with a clearer understanding of risk, and use their findings to strengthen defenses.
How does preemptive MDR differ from traditional MDR?
Managed detection and response provides security specialists who monitor, investigate, and respond to threats around the clock. Many services also include proactive threat hunting and recommendations to improve security.
Preemptive MDR connects that work more directly to what makes an organization vulnerable. When analysts investigate suspicious activity on a server, knowing that it is internet-facing, supports a critical application, and has a vulnerability under active exploitation helps them assess urgency and determine where to look next.
In Rapid7’s model, exposure findings inform investigation and remediation priorities, while investigations reveal weaknesses that need attention. Security leaders gain a clearer connection between the threats their provider handles and the conditions their organization needs to address.
Within a broader preemptive cybersecurity strategy, MDR connects exposure information with the people investigating and responding to threats. The aim is to reduce opportunities for compromise and intervene before an attack causes harm, while retaining the expertise to contain and recover from incidents.
How exposure context and proactive threat hunting inform MDR
By combining information about assets, vulnerabilities, business criticality, and attacker behavior, preemptive MDR helps teams decide which weaknesses require action first. Exposure context also informs targeted hunting and the investigation of suspicious activity.
Consider a hypothetical organization running an internet-facing application affected by a newly disclosed vulnerability. The security team needs to establish whether the vulnerable software is present, what the application supports, and whether attackers are exploiting the weakness.
Those findings can guide remediation priorities and targeted hunting for signs of compromise. If suspicious activity appears, analysts investigate it with an understanding of the affected system and the potential route an attacker could take through the environment.
Depending on the evidence, the response may involve containing a system, examining related accounts, or expanding the investigation to other assets. The organization’s remediation teams also need clear recommendations about the underlying exposure.
What the investigation reveals then feeds back into detection rules, hunting priorities, and response procedures. This gives leaders a way to track an identified risk through investigation, action, and outstanding work, with clearer ownership at each stage.
What role does AI play in preemptive MDR?
Before analysts can assess a potential threat, they often need to retrieve logs, examine user activity, and connect evidence across several systems. AI can accelerate this work by gathering and correlating information for review.
Agentic investigation capabilities can perform elements of that process in parallel, test possible explanations, and organize findings. Their usefulness depends on the available data: missing identity activity or asset information can leave gaps in the account of what happened.
Rapid7’s approach keeps human expertise central to validation and response decisions. Analysts assess the evidence alongside the organization’s priorities and the consequences of an action, including whether isolating a system could interrupt a critical service.
What to look for in a preemptive MDR provider
When evaluating a service described as preemptive, ask the provider to show how exposure information changes its work. A redacted investigation should make clear what analysts knew about the affected asset, how that influenced their reasoning, and which actions followed.If an investigation identified a weakness, was it assigned to an owner and addressed? Did the findings change detection coverage or future priorities? Where AI contributed, the provider should explain its role and the oversight applied.
Incident response remains part of the requirement. Rapid7 MDR includes unlimited incident response alongside exposure-informed defense and AI-assisted investigation, supporting containment, detailed analysis, and threat eradication.
Agree on responsibilities before that support is needed. Establish which actions the provider can take, when customer approval is required, and who owns remediation. Those arrangements determine how findings become action, particularly when taking a system offline carries business consequences.
Once the service is operating, review progress through specific cases: exposures addressed before exploitation, threats contained, and weaknesses closed after investigation. Ask to see the evidence behind those outcomes and any work still outstanding, so your team can judge where risk has changed and where further attention is needed.
Explore Rapid7 MDR to see how exposure-informed defense, AI-assisted investigation, and expert response work together.
Spying on Governments with Zero Lines of Malware: A Custom SoftEther Bridge in Webworm’s Toolkit
Post Syndicated from Milan Spinka original https://www.rapid7.com/blog/post/tr-spying-on-governments-no-malware-custom-webworms-toolkit-softether-bridge
Introduction
For a threat actor, the perfect malware is one they don’t have to write, and already does all they need. One example of this is shown by the China-aligned APT known as Webworm, which has been known to deploy the open-source SoftEther VPN into the networks of compromised governmental organizations to maintain low-profile, long-term access.
After this was publicly documented and defenders could keep an eye out for this tactic, the actor presumably started thinking of ways to make their covert access stealthier. In this post, we share our analysis of what we believe to be a so-far unknown custom SoftEther-based tool, which implements various tricks to hide itself from security tools, and which we attribute to Webworm with moderate confidence. We additionally provide guidance and tooling for detecting its presence on a system and extracting the configuration(s) associated with it.
Technical analysis
To illustrate how the tool works, we will use the only public sample of this tool we are aware of, which can be found in our IoCs list (90e7…).
The sample is a Windows PE32+ file targeting the x64 architecture. Based on cleartext strings and constants in the binary, we identified it as a (modified) build of the SoftEther VPN Bridge executable, specifically version 4.44, build 9807. Similarly, the PDB path included in the executable reads C:\Users\Administrator\Desktop\SoftEtherVPN_Stable\SoftEtherVPN_Stable\SoftEtherVPN_Stable\src\DebugFiles\pdb\x64_Release\vpnbridge.pdb. As such, the tool doesn’t hide its identity from reverse engineers, only external interactions.
The first and most trivial change the threat actor implements is in the PE metadata. Here we learn that the OriginalFileName of this binary is netcapa.exe, and it brands itself as “Network Monitor Software” published by a company named “Network Systems Solutions Inc.“. The only field unchanged against the stock SoftEther executable (vpnbridge_x64.exe) is the Version, which reads 4, 44, 0, 9807.
Next, we wanted to identify any functionality added or modified by the threat actor. The SoftEther bridge alone is a powerful tool to maintain remote access to a compromised network, but we wanted to know if perhaps there was a backdoor to give the threat actor direct command execution on the infected host. For that reason we checked out the corresponding tag in the public “SoftEtherVPN_Stable” repository on GitHub and compared it to the decompiled sample.
Internal rebranding
The rebranding apparent in the exposed metadata extends into internal strings used in debug banners, service names, registry keys, the contents of the server’s HTTP 401 error page, or firewall rule names, where occurrences of “SoftEther VPN” are replaced by “NtMonitor VPN”.
However, the renaming is inconsistent; for example, the service name used by the entry point is still SEVPNBRIDGE, and many registry key paths still reference the “SoftEther Project”.
Network stealth
Stock SoftEther VPN Mayaqua/Network.h defines HTTP endpoints used by the protocol:
HTTP_VPN_TARGET   "/vpnsvc/vpn.cgi"
HTTP_VPN_TARGET2  "/vpnsvc/connect.cgi"
NtMonitor replaces these endpoints with much more innocent-sounding names, in particular:
HTTP_VPN_TARGET   "/update/alive.cgi"
HTTP_VPN_TARGET2  "/update/picture.cgi"
A client initiating a connection to a SoftEther VPN server will send a handshake request to HTTP_VPN_TARGET2 along with a “watermark”, i.e. a byte pattern proving that the client is speaking the correct VPN protocol. Otherwise, the server answers with a decoy HTTP response.
NtMonitor changes the upstream GIF watermark with a custom byte pattern (a truncated PNG file showing the Windows logo), so that stock SoftEther clients and servers cannot handshake with this build, and NtMonitor’s own peers cannot be fingerprinted with the well-known stock GIF watermark.
Embedded resource archive
As the threat actor probably realizes, a SoftEther resource archive named hamcore.se2, which sits next to the executables in the installation directory and is required to be present at runtime, provides a straightforward detection opportunity for unauthorized installations. We think that, for this exact reason, the actor chose to reduce the contents of this archive to a bare minimum, package the archive inside the bridge executable itself (as a PE resource), and implement a custom resource directory walk to load the archive at runtime. As a side effect, this increases the binary’s size by about 1.5 MB compared to the official build.
Encrypted configuration
Another weak point (for the attacker) in stock SoftEther is that its configuration is stored on disk in plain text in a well-recognizable format. The actor changes its name from vpn_bridge.config to setting.conf and modifies the configuration loader to handle custom-encrypted files that start with the magic bytes RCEN in ASCII. The rest of the encrypted file has a simple format and includes the encryption key. A Python script to decrypt such files with the actor’s custom RC4-like cipher is available on the Rapid7 Intelligence GitHub repository.
Attribution and interpretation of findings
Beyond the changes described above, we did not identify any additional malware functionality. Clearly, the threat actor prioritizes stealth above raw capability. It seems like they methodically analyzed SoftEther’s detection surface and implemented counter-measures to all of the easy ways a detection engineer may target it. At the time of our analysis, only one anti-virus vendor detected the sample on VirusTotal, although it has been public since January.
This aligns well with the TTPs previously reported for Webworm by ESET, and such attribution is further supported by indicators in decrypted configurations Rapid7 Intelligence has access to. In all of the cases, the VPN is configured to bridge (“cascade”) a remote network into the local one; furthermore, in cases that were not likely deliberate tests, the remote IP address was located inside AS 20473 belonging to The Constant Company, LLC, which (also including its subsidiary, Vultr) has been associated with Webworm on many occasions in the past.
Considering this attribution, we can put together some important takeaways: Quite likely, we are looking at a new evolution in the tooling used by Webworm, a China-aligned APT whose activity is known to focus on governmental organizations, especially in Europe. Earlier this year, ESET already noted this group to shift away from custom malware to dual-use tools such as SoftEther VPN, but now we are observing a sort of hybrid of the two — stock SoftEther software that is not trojanized, but rebuilt from source in a way that erases much of its detection fingerprint.
Detection guidance
To detect this particular variant of Webworm’s tooling, we provide a list of IoCs and a YARA ruleset on our public GitHub repository. If you have the ability to inspect TLS traffic in your organization, one of the most reliable detections you can deploy right now is to look for POST requests to /update/picture.cgi with Content-Type: image/jpeg and a request body starting with and 89 50 4e 47 0d 0a 1a 0a 00 00 00 0d 49 48 44 52 (initial bytes of the custom PNG watermark).
Although the samples we have seen all use the same NtMonitor branding internally (despite the PE metadata differing across samples), this is the easiest change for the threat actor to implement next. Similarly, the HTTP endpoints and watermark can be swapped out trivially. As such, we recommend defenders in the government sector to familiarize themselves with intrinsic SoftEther VPN behavior in order to stay one step ahead of when the threat actor decides to update the tool next.
MITRE ATT&CK techniques
|
Technique ID |
Technique Name |
Comment |
|
T1587.001 |
Develop Capabilities: Malware |
The actor is maintaining their own fork of SoftEther VPN used for malicious purposes. |
|
T1027.013 |
Obfuscated Files or Information: Encrypted/Encoded File |
Configuration files are encrypted with a custom cipher. |
|
T1140 |
Deobfuscate/Decode Files or Information |
Encrypted configuration files are decrypted at startup by the modified loader. |
|
T1036.005 |
Masquerading: Match Legitimate Resource Name or Location |
PE metadata is purposefully changed to masquerade as a generic system service. |
|
T1027.005 |
Obfuscated Files or Information: Indicator Removal from Tools |
Known SoftEther artifacts are systematically removed from the binary. |
|
T1686.003 |
Disable or Modify System Firewall: Windows Host Firewall |
Using stock SoftEther functionality, the malware adds rules to the system firewall. |
|
T1599 |
Network Boundary Bridging |
The VPN bridge binds together the infected host’s local area network with the attacker’s. |
|
T1071 |
Application Layer Protocol |
C2 communication uses HTTP(S) and SoftEther’s application protocol. |
|
T1090.001 |
Proxy: Internal Proxy |
The infected host serves as an internal proxy mediating C2 access to other hosts on the network. |
PHP 8.6.0 released
Post Syndicated from jzb original https://lwn.net/Articles/1108555/
Version 8.6.0 of
PHP has been released. Notable changes in this release include a polling API, a
new clamp() function, a SortDirection enum, and a
\Time\Duration class. See “What’s new in 8.6”
for more on new features, and the changelog for a full list
of changes.
Four PHP security releases including fixes for critical vulnerabilities
Post Syndicated from jzb original https://lwn.net/Articles/1108552/
The PHP Project has announced the release of PHP 8.5.13, 8.4.28, 8.3.37, and 8.2.36. Each contains a
number of security and bug fixes, including several fixes for critical
vulnerabilities that could allow remote-code execution. According to the
project’s pre-release
announcement on November 18, all of the vulnerabilities of critical
severity “require either non-default configuration or uncommon
“. See the release notes for details; Linux vendors and projects
setups
should be releasing updated packages soon.
Security updates for Thursday
Post Syndicated from jzb original https://lwn.net/Articles/1108551/
Security updates have been issued by AlmaLinux (cockpit, cockpit-files, cockpit-machines, gimp, glib-networking, krb5, libpcap, nginx, nodejs26, perl-CGI, php8.4, skopeo, tigervnc, and xorg-x11-server), Debian (haproxy, libreoffice, libvisio, needrestart, openjdk-21, and openjdk-25), Fedora (asterisk, erlang, ffmpeg, ignition, libosmocore, luksmeta, msedit, openapv, passwordsafe, rabbitmq-server, sngrep, and vyper), Mageia (firefox, nss, rootcerts, rsync, and thunderbird), Slackware (libfontenc and libXfont2), SUSE (389-ds, apache2, aspell, bind, brotli, busybox, civetweb, containerd, cosign, docker, gleam, glibc, graphicsmagick, helm, ignition, ImageMagick, java-17-openjdk, java-21-openjdk, java-25-openjdk, jhead, kernel, kubernetes, libsofia-sip-ua-glib3, mcphost, perl-HTTP-Body, perl-MIME-tools, phodav, python-asyncssh, python-django, python-joserfc, python315, qemu, rootlesskit, roundcubemail, rsyslog, runc, tempo-cli, trivy, and xorg-x11-server), and Ubuntu (cloud-init, gstreamer1.0, hplip, libcpanel-json-xs-perl, linux, linux-aws, linux-aws-5.4, linux-aws-fips, linux-azure-5.4, linux-azure-fips, linux-bluefield, linux-fips, linux-gcp, linux-gcp-5.4, linux-gcp-fips, linux-hwe-5.4, linux-ibm, linux-ibm-5.4, linux-iot, linux-kvm, linux-oracle-5.4, linux-raspi, linux-raspi-5.4, linux-xilinx-zynqmp, linux, linux-aws, linux-kvm, linux-lts-xenial, linux-azure, linux-oracle, linux-azure-7.0, linux-fips, nginx, openjdk-17, openjdk-21, openjdk-25, openjdk-27, and openjdk-lts).
Internet traffic and attacks during the 2026 U.S. midterm elections
Post Syndicated from Patrick Day original https://blog.cloudflare.com/internet-traffic-2026-us-election/
Visitors to government election websites surged 363% on November 3, the date of the 2026 midterm elections in the United States. Across Cloudflare's election protection programs, we also detected a significant shift in the types and timing of cyberattacks throughout 2026.
Unlike what we saw in other recent elections, attackers focused on gaining access to internal systems and data, rather than knocking websites offline. Government election websites faced website vulnerability attempts 180 times more often than denial-of-service (DDoS) attacks, and at roughly ten times the rate of Cloudflare's broader customer base. We also found evidence of at least one attempt to exploit a recently disclosed critical PHP vulnerability on a state government voting website in the Western United States.
These attacks peaked in late October, several weeks before the election. Vulnerability exploit attempts climbed steadily throughout 2026: from 200,000 per day in January, to 2 million per day in October. However, on Election Day in the U.S., Cloudflare detected no escalation in attack volume and zero major DDoS incidents across protected election sites, marking a sharp contrast to other recent elections, such as in Moldova last year.
Our data regarding cyberattacks on election institutions came from organizations participating in Cloudflare's free cybersecurity programs: the Athenian Project, Cloudflare for Campaigns, and Project Galileo. Together, these initiatives helped protect more than 1,400 election-related websites during the 2026 U.S. midterm elections, including those belonging to state and local governments, candidates, political parties, voting-rights advocates, journalists, and civil society groups.
Cloudflare launched its first election protection program in 2016 after widespread reports of cyberattacks targeting the U.S. elections. A decade later, it is remarkable to see how far governments and campaigns have come in securing their digital infrastructure. We are proud to help protect democratic institutions and are encouraged that cyberattacks were once again not a disruptive factor in 2026.
In this post, we examine traffic and attacks observed against those organizations on Election Day, analyze the most common types of attacks of the 2026 cycle, and provide recommendations based on those findings.
Election Day: significant voter traffic, minimal attacks
Ordinary user traffic to state and local government election websites was higher on Election Day (November 3) than any other day in 2026. Traffic to those sites increased to approximately 602 million requests, up from 130 million on November 1. By comparison, traffic across the rest of Cloudflare’s global network rose by only 12% over the same period.
State and local government election websites provide authoritative information to voters on how to register, where to vote, and who won. Because of their critical role, these platforms are often targeted by those seeking to suppress voter turnout, disrupt the reporting of results, or steal sensitive information.
On Election Day itself, Cloudflare did not record a single significant distributed denial-of-service (DDoS) attack across any of its 1,400 election-related websites. The only significant DDoS attack occurred on November 2, targeting a candidate for the U.S. House of Representatives in California and totaled 520,000 requests. By comparison, the Moldovan Election Commission experienced more than 898 million malicious requests in a single 12-hour period on their Election Day in 2025, with attacks peaking at 324,333 requests per second.
Prior to Election Day: the most common attacks in the 2026 cycle
Website vulnerability scans were by far the most common attack observed by Cloudflare in the 2026 U.S. election cycle. In the 12 months leading up to the election, Cloudflare mitigated 392 million such attacks on government election websites alone.
Website vulnerability attacks exploit outdated or vulnerable website code to gain access to internal systems and data. For example, cross-site scripting attacks inject malicious code into web pages in order to capture administrator credentials or deface site content. SQL injection manipulates database queries allowing attackers to potentially extract voter records or alter data.
Phishing and other malicious emails targeting political campaigns protected by the company occurred at rates consistent with Cloudflare's broader network, but showed signs of sophistication. In the 90 days leading up to the election, 3.9% of emails sent to organizations participating in Cloudflare for Campaigns were identified as malicious, closely tracking the 4.8 percent baseline across other Cloudflare customers. However, nearly 42% of those malicious emails managed to bypass basic email authentication checks, such as verifying sender identity or preventing in-transit tampering. These threats were nonetheless identified by Cloudflare’s advanced phishing detection tools.
Although website vulnerabilities were the most common attack overall, for journalism and election-related civil society organizations, DDoS was the most common. Over the same 12-month period, Cloudflare mitigated over 10.8 billion DDoS requests targeting these groups. The largest single attack occurred on September 10, 2026, hitting a U.S.-based news organization with 3.04 billion requests. This pattern is consistent with Cloudflare research released earlier this year, which found that among all Project Galileo entities in 120 countries, DDoS were by far the most common attack seen, accounting for 81% of all attacks.
PHP vulnerability
On October 21, security researchers disclosed serious vulnerabilities (known as php2shell) in PHP, an open source back-end programming language used by 70% of the world's websites. The flaws reportedly could allow attackers to execute malicious code on vulnerable servers, expose customer data, or disrupt services. Cloudflare deployed Web Application Firewall (WAF) protections for all customers, prior to public disclosure of the vulnerability.
On October 22, Cloudflare's PHP defense was triggered more than 9,000 times on a state government election website in the Western U.S. This attack was only detected on one election-related site and appears to have been an isolated incident rather than part of a broader trend.
Recommendations
Cloudflare research consistently shows that individuals and organizations participating in democratic elections face significant risk of cyberattack. Data gathered during the 2026 U.S. midterm election suggests those attacks continue to evolve, occur throughout an election cycle and not only on Election Day, and can vary depending on the type of organization targeted.
Based on the recent cyberattack trends in the 2026 U.S. midterms and other elections, we make the following recommendations:
- Prepare for surges in user traffic. Legitimate voter interest can create traffic spikes that overwhelm unprepared infrastructure and make essential election websites inaccessible. Organizations should prepare scalable, efficient infrastructure to handle Election Day traffic increases without straining budgets or staff.
- Maintain security protections year-round, not just on Election Day. Cyberattacks targeting democratic institutions occur across the entire election cycle, not just around voting windows. Defensive postures must remain active continuously rather than treated as a short-term, seasonal measure.
- Deploy automated defenses to counter rapid threats. AI has made it easier for attackers to find and exploit new vulnerabilities. Organizations should implement security services that update automatically, like managed rules, to ensure new protections deploy by default.
Ensuring voters have access to reliable information about elections not only helps encourage participation and deliver timely, accurate results, but also protects voter confidence in the democratic process itself. As more officials, more institutions, and the public increasingly rely on the Internet for those services, keeping that digital infrastructure stable, secure, and accessible becomes an essential civic priority.
State and local election offices, political campaigns, party organizations, journalists, and voting rights groups in need of cybersecurity services can access them from Cloudflare at no cost. Visit the Athenian Project (for state and local election websites), Cloudflare for Campaigns (for political campaigns), or Project Galileo (for civil society, democracy, and journalism organizations) to learn more about eligibility and sign up today.
Could Congress Address Elon Musk’s Role in Foreign-Policy Decision Making?
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/7ge_0a3GXp0
Suing Our Way Out of Climate Change
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=IkWrPac_Psw
Професия: Съдебен заседател (втора част)
Post Syndicated from Стефан Иванов original https://www.toest.bg/profesiya-sudeben-zasedatel-vtora-chast/
<< Към първа част
Ясно помня първите си две дела. Помня ги с тялото повече, отколкото с паметта. Лекото гадене, сухата уста, усещането, че температурата ми се вдига с половин градус на всеки етаж. Пиех вода, мачках пластмасовата бутилка, беше горещо и задушно. Вътре никой не пушеше. На всеки етаж имаше балкони и там, между саксии с изсъхнали мушката, в общ облак димяха адвокати, призовкари и подсъдими – демократично и с липсващо процесуално разделение на ролите.
Въпросът, който ме глождеше, беше простичък и неприятен:
Имам ли подготовката, а и правото да правя това?
Бях чел, естествено. Бях минал онлайн обучението, бях решавал тестове и получих отлични резултати, което ме успокои приблизително колкото шофьорската книжка успокоява съвестен човек, който за първи път излиза на магистрала. Бях се оправил и с електронния подпис, с който получавам достъп до материалите и с който по-късно подписвах делата. Официално обаче още не бях заклет. Законът изисква съдебните заседатели да положат клетва пред общото събрание на съдиите, но заради ковид протоколите тържествеността беше отложена и влизах в съдебната власт някак странично, през служебния вход на процедурата. Обучението ме беше въвело в етичните правила, записани в наредбата за съдебните заседатели, сред които са
безпристрастност, дискретност, задължение за отвод при най-малкото съмнение за личен интерес.
Звучеше като устав на средновековен орден, преведен на езика на държавната администрация. Носех го в главата си, сякаш беше наръчник, който предстои да изпробвам на терен.
Сградата живееше свой собствен живот. Служители бутаха огромни колички, натоварени с папки като пощальони от деветнайсети век. Вратите се отваряха с пропуски, които никога не сработваха от първия път. Обикалях гишета, питах, получавах отговор, който пораждаше нов въпрос, и през цялото време ме съпровождаше кафкианското подозрение, че съм в грешна стая, объркал етажа, часа и деня. Кафка, юрист по образование и чиновник в застрахователен институт, е знаел добре, че
ужасът на закона живее най-вече в коридорите и пред вратите.
Първото ми заседание беше за дело със 17-ти състав, при съдия Петров. Залата не беше обявена предварително и се оказа №21. Чаках, вълнувах се и същевременно ме обземаше онази скука, която придружава всяко чакане, независимо от залога. До мен седяха две възрастни жени, дошли за друго дело, разговаряха за цените на доматите и за внуците си, което някак ме успокои, всичко беше нормално, животът продължаваше да си тече тихо и познато. Другата съдебна заседателка се казваше Мария Георгиева, работеше в отдел „Човешки ресурси“ на голяма банка и се занимаваше с трудово право, а мъжът ѝ от двайсет и пет години беше адвокат по наказателни дела. Тя имаше спокойствието на човек, слушал юридически истории всяка вечер от поне четвърт век. Съдията закъсня с двайсет минути.
Подсъдимият беше бездомен човек, бивш огняр, вписан като управител на фирма за търговия на едро със захар и олио, която не беше платила данък добавена стойност за над 7 милиона лева.
Подставено лице, сламен човек, както казват юристите, на хартия собственик на империя, която никога не беше виждал. Обвинението беше по член 255 от Наказателния кодекс за избягване на данъчни задължения в особено големи размери. Седеше със старото си яке, гледаше пода и вероятно не би могъл да обясни какво е ДДС.
Хана Аренд, германско-американска философка, говори за баналността на злото в съвсем различен мащаб. Атмосферата беше подобна на онази в залата с крехкия и тъжен човек, натоварен с огромната сума. Прокурорът прочете обвинителния акт с равен, леко уморен глас, в който числата звучаха абстрактно. Служебният защитник, млад и съсредоточен, подреждаше листовете си с педантичността на шахматист. Съдията обясни на подсъдимия правата му бавно, изречение по изречение, с търпението на начален учител и го попита дали е разбрал. Той кимна. В бележника си записах първото си впечатление, три думи, които по-късно зачеркнах, защото присъдата се ражда от доказателствата и от времето.
Делото започна с онова, което наричам юридически катехизис. Покажете лични карти. Имена, дата на раждане, адрес. Към свидетелите и вещите лица винаги ехти „Дела и родства със страните имате ли?“ – въпрос с почти библейска интонация, който след десетото повторение звучи като литания. Предупреждение за наказателната отговорност при лъжесвидетелстване. Подпис. Ритуалът има своя смисъл, разбира се, той удостоверява, че всички в залата са тези, за които се представят, и знаят какво се случва. Театралният човек в мен веднага забеляза мизансцена, издигнатата маса на състава, прокурора от едната страна, защитата от другата, свидетеля в центъра, с гръб към публиката като в античната орхестра.
След заседанието трябваше да отида в информационното обслужване за още една подробност за електронния подпис, после да се върна в деловодството и да кажа какво става с делото, дава ли му се ход и кога е следващото заседание. Отговорността да следиш се оказва изцяло твоя, т.е. моя. Някой ден през седмицата трябваше да занеса и напечатана банкова сметка за възнаграждението и в стая 112 ме чакаха материалите от обучението.
Правосъдието, научих бързо, се състои от големи принципи и безкрайно много малки хартийки.
Второто заседание в същия ден беше за по-дребно и тъжно престъпление. Кражба на телефон и 30 лева от две момчета от „Надежда“, по член 194. Малка зала, съдийката закъсня, другият съдебен заседател, възрастен господин с вратовръзка, ми прошепна, че съучастничката на единия подсъдим много прилича на негова бивша колежка от завода. Не беше тя. Бързо ми стана ясно колко лесно личното се вмъква в правосъдието и колко важно е заседателите да идват от различни светове. Момчетата дойдоха като свидетели заедно с майките си, облечени официално като за абитуриентски бал и разказваха с точността на хора, преповтаряли историята пред приятели десетки пъти. Трийсетте лева имаха в залата същата процесуална тежест като седемте милиона от сутринта. Ритуалът беше същият, катехизисът също, лични карти, дела и родства, подпис. В това равенство пред процедурата има нещо дълбоко демократично и леко абсурдно, което Чехов би оценил.
Още след тези две дела разбрах няколко неща, които противоречаха на представите ми. Съдебната система функционира доста по-ефективно, отколкото предполагах. Има срокове и те се спазват, ясно е кой какво върши и защо. Делата се разпределят на случаен принцип чрез електронната система на съдилищата, същата логика определя и кои заседатели ще седнат в състава. Тази лотарийна справедливост, която древните атиняни са ценели при избора на своите съдии, ми се стори едновременно модерна и стара колкото самата демокрация. Видях колко широки са правомощията на съдията в залата и колко голяма власт има прокуратурата. Тя решава кое дело изобщо ще се добере до съда и в какъв вид, стига да реши да използва силата си отговорно и адекватно. Разбрах и нещо по-обезпокоително.
Средностатистическият съдебен заседател често е бивш служител на МВР, на съдебната система или роднина на такъв.
Така институцията, замислена като глас на обществото, рискува да се превърне в ехо, рима и копие на самата система. Нилс Кристи сигурно би се намръщил и би написал петиция.
Кристи, норвежки криминолог, в есето си „Конфликтите като собственост“ от 1977 г. описва модерния съд като място, където конфликтът се отнема от хората, на които принадлежи. Пострадалият се превръща в свидетел по собственото си дело, извършителят – в обект на процедура, а общността наблюдава отстрани. Предложението му е съд, ориентиран към пострадалия и към квартала, с участието на непрофесионалисти, където страните се срещат лице в лице и говорят за щетата, причините, възможната поправка и едва след това за наказанието. Тази идея се превръща в една от основите на възстановителното правосъдие, развито по-късно от Хауърд Зер, американски криминолог, и приложено в практики като медиацията между пострадал и извършител, семейните конференции в Нова Зеландия, вдъхновени от традициите на маорите, и възстановителните кръгове в Канада.
Смисълът е прост и дълбок: престъплението наранява конкретни хора и отношения и правосъдието има задачата да ги възстанови, доколкото е възможно. Изследванията в редица страни показват по-висока удовлетвореност сред пострадалите и по-малко рецидиви сред извършителите, участвали в такива срещи. В България подобни практики живеят предимно в пилотни проекти и в работата с непълнолетни. Съдебните заседатели обаче са готов мост към тях. Те са хора от квартала, носители на житейски опит и здрав разум, които могат да внесат в съда въпросите на Кристи за това кой е пострадал и как може да се поправи вредата. Двете момчета от „Надежда“ и майките им заслужаваха и такъв въпрос.
Възстановителното правосъдие – опит за помирение
Възстановителното правосъдие е тема, която не е много позната на широката публика в България, макар че страната ни има традиции в тази насока. За нас е истинска чест, че двамата съдии Мирослава…
Успокоявах се постепенно и бавно след този първи ден – кортизол и адреналин се бяха смесили във висока доза. Никога няма да забравя специфичната лекота, която изпитах тогава и изпитвам всеки следващ път, щом напусна съда и изляза на въздух. Никой не ме преследва, не ме отвежда с белезници, правата ми не са ограничени. Мога да пътувам, да спра да послушам уличните музиканти, да отида на работа в Театрална работилница „Сфумато“, да продължа кореспонденцията за гостуване в Румъния, да вляза в онлайн среща на борда на директорите на Съюза на театрите на Европа, да преговарям за авторските права на Бекет и на Дънкан Макмилан. И да очаквам с нетърпение да стана баща. Свободата, оказва се, се усеща най-ясно на изхода на съда. В следващия текст ще разкажа за различните и най-чести дела, с които се срещнах отблизо, и за хората, които излизаха през същата врата, без да усетят лекота.
(Следва продължение.)
С оглед на тайната на съвещанието и защитата на личните данни всички имена, номера на състави и зали, суми, предмети на делата и обстоятелства по тях са променени. Всяка прилика с действителни лица и дела е случайна.
На второ четене: „Тесният път към далечния север“
Post Syndicated from Антония Апостолова original https://www.toest.bg/na-vtoro-chetene-tesniyat-put-kum-dalechniya-sever/
„Тесният път към далечния север“ от Ричард Фланаган
превод от английски Владимир Молев, София: изд. „Колибри“, 2016, 2025
Гостуването на един от най-емблематичните съвременни писатели – австралиеца Ричард Фланаган, съвпадна с премиерата на току-що издадената му у нас квазимемоарна книга „Въпрос 7“, както и с ексклузивната прожекция (в рамките на кинофестивала „Синелибри“) на първия епизод от минисериала „Тесният път към далечния север“. Именно за едноименния адаптиран роман на автора, удостоен през 2014 г. с наградата „Букър“, ми се иска заслужено да припомня тук. Той излезе у нас през 2016 г. в превод на Владимир Молев, а миналата година се появи във второ, обновено издание с нова корица.
Имах щастието да взема интервю от Фланаган преди срещата му с българските читатели. Разговарях с един уморен от огромната часова разлика човек, наясно със своята популярност, подготвен да говори при всякакви обстоятелства и с отработен автоматизъм по няколкото стандартно извеждани теми, отразяващи най-вече любопитството на читателите към неговата непозната и далечна родна Тасмания. Бързо стана ясно обаче, че за трийсетте минути (след предвидените петнайсет) просто няма как да покрием, камо ли в дълбочина, всички дълбоки екзистенциално-философски въпроси, които четирите му издадени у нас книги повдигат. В този материал ще маркирам и някои от тези незададени питания.
Фланаган справедливо е отбелязвал, че всички негови романи в крайна сметка могат да се разглеждат като автобиографични. Действително цялото му творчество може да се разглежда като един метатекст, в който прототипи, мотиви и сюжети мигрират. „Въпрос 7“ обобщава по биографично-мемоарен начин големите събития и теми, които писателят фикционализира толкова успешно от дебютната си книга „Смъртта на речния водач“ насам (базирана на давенето му в река Франклин, когато буквално е върнат от смъртта). Всичко това е свързано и с осъзнаването, че писането неизбежно е отражение на собствените ни формални, психически и аналитични опитности, и най-вече с идеята за паметта като форма на въображение, като творчески жест към миналото, което тя възстановява, запълва и подрежда така, както един писател гради сюжетите си.
Сред тези големи теми, които сякаш не просто занимават, а истински обсебват автора, са и преживяванията на баща му Арчи Фланаган като военнопленник през Втората световна война. Върху тях той построява своя букъров епос „Тесният път към далечния север“, но продължава да се връща и в редица нехудожествени текстове и статии, и във „Въпрос 7“. Докато за този последен роман Фланаган посещава лагера Охама в Япония, където баща му е бил подложен на принудителен труд във въглищна мина, и се връща към собствените си спомени за него, то в „Тесният път към далечния север“ той се пренася в годините преди това, към т.нар. линия на смъртта – железница, която австралийски и други военнопленници прокарват в джунглата между Сиам (Тайланд) и Бирма под контрола на японците.
И докато „Въпрос 7“ е фин ретроспективен опит за осмисляне и отдаване на почит към преживяното от бащата, но и любящ поглед към отраженията на този травматичен опит върху неговата личност и живот по време на израстването на самия Фланаган, то „Тесният път към далечния север“ не се пести и разгръща в зрелищна вакханалия случилото се на линията на смъртта, драматизира по смазващо графичен начин разказите за непосилните условия, (само)убийствената йерархия и нечовешкия принудителен труд, на който са подложени военнопленниците.
Нещо повече. Докато в мемоарната книга става ясно, че с времето Фланаган-старши е подложил паметта си за тези събития на опрощаваща редукция, пресявайки с годините спомена за злото до една съхраняваща, смиряваща и осмисляща идея за любовта, то в романа си Фланаган е заместил – и облекчил – баща си (прототипа на протагониста Дориго Еванс) в натуралистичното обговаряне на човешката жестокост, в невъзможността да избягаш от бремето на миналото.
Забравянето може да е форма на спасение или съпротива, но в „Тесният път към далечния север“ протагонистът е наказан с помнене.
И ако един друг роман на Фланаган, излязъл в началото на годината – „Живо море от сънища наяве“, може да се нарече роман за изчезването и своеобразна критика на егоистичната антропоцентрична индустрия на индивидуалното безсмъртие за сметка на колективното планетарно опустошение, то „Тесният път към далечният север“ е класическа поема за оцеляването. За неговата – много меко казано – неестетична прагматичност, за неговата живителна гнусота, за неговия „просветен егоизъм“, развенчаващ плакатните разбирания за алтруизма и героизма.
Именно този „просветен егоизъм“, както по-късно Фланаган го дефинира при един разговор с баща си, бива демонстриран чрез случващото се в „Тесният път към далечният север“ – насред душните и влажни гори на Сиам, калта и изпражненията, глада и безмилостните насекоми, болестите и гниенето на плътта и духа човешки. Осъзнаването, че единствено в спойка с другите, чрез отстъпки и жестове към тях увеличаваш шанса си сам да оцелееш, подрива саможертвената патетика и юначните жестове в името на един откровен и прагматичен кодекс на оцеляването.
Тази рецепта за съхранение, следвана от австралийските военнопленници (за разлика от японците, които мрат като мухи, макар те да са „господарите“ в тази история), е базирана на скъсването с йерархията. Едно от най-ясните осъзнавания в романа е, че традиционно възхваляваната желязна йерархия в японското общество, смятана за непоклатим гарант за ред, ефективност, стабилност и най-вече зачитане, всъщност е колос върху глинени крака. Абстрактната идеализация на горестоящия, чак до божествената неприкосновеност на императорската воля, се осъществява с цената на свръхчовешко усилие, вредно себеизличаване и разпадаща се човешка логика. Те много повече виктимизират и поставят под съмнение контрола и властта, отколкото там, където офицерите измежду военнопленниците споделят своите заплати с редовите войници, разпределят дажби и проявяват уж алтруизъм и милосърдие. Да се положиш за другия в името на себе си е изведено като парадоксалната формула на това оцеляване.
Чрез своите герои Фланаган ни представя различни защитни механизми за справяне с безсмислието на жестокостта и злото, издигнати почти до мистичен феномен, необясними до отвъдност. Ала завладяващото в тази история не е дори някакво дълбоко екзистенциално осмисляне на страданието, а простичкият, понякога до нелепа трагикомичност начин, по който събраните от кол и въже мъже го рационализират, понасят и абсорбират. Насред бруталността мъжеството се проявява дори в липсата на съпротива, в самото изтърпяване на безсмислието. Фланаган не е сантиментален дори когато е чувствителен, дори когато говори умилителния език на човечността. Грубоватата, посредствена и несъвършена човечност, понякога по-скоро дори случайна, насилена под напора на обстоятелствата, отколкото плод на съзнателно героично усилие.
На този фон е логично да се запитаме дали Фланаган не ни предлага една картина, която опровергава онзи известен израз на св. Августин. Защото не е ли всъщност именно доброто временна липса на зло – бърз, недостатъчен опит истината за първоначалието на злото в света да бъде скрита? Не успях да попитам Фланаган, но ми се струва, че не би се съгласил – нищо че в романа сам опровергава стойността на оцеляването. Резюмирайки случилото се с всеки от героите на романа след войната, той ни показва неокончателността на този процес, цената на оцеляването, спестеното на загиналите.
Посттравматичното стресово разстройство, официално въведено като термин през 80-те, е било непознато по онова време, но мнозина от мъжете очевидно страдат от него под една или друга форма през целия си живот. Оцеляването се превръща в ахронично хронично състояние. Изпражненията, въшките, холерата и боят в лагера съществуват сублимирани – паралелно с известността, интервютата и официалните коктейли в късните години на този успешен хирург, произведен в национален герой по силата на оцеляването си, по силата на това, че носи травмата да е жив.
Фланаган изобличава не автентичността на героизма, а кухото му провъзгласяване за такъв от ония, които не са понесли неговия провал.
Този дълбоко, но невидимо пропукан образ днес е емоционално вцепенен авторитет, провалил се съпруг, сериен прелюбодеец и парадоксално, единственото му опрощение е в отнетото му право на любов.
Ако има една линия, която атемпорално събира и надмогва всички останали времеви линии в романа, то това е невъзможната почти до имагинерност любов на Дориго Еванс към съпругата на чичо му. Любов, която едновременно боли и лекува, съшива и разнищва, противопоставя своя екстазен ад на мъчилището в джунглата. Подобно на нея, Фланаган още в името на романа противопоставя в жестока ирония възвишената поезия (заглавието е цитат от Башо) на институционализираното и идеологически идеализираното варварство. Метафората на красивото духовно търсене при Башо е буквализирана в прокарването на застлан с човешки трупове и изпражнения брод през джунглата.
Както във всяка добра литература, Фланаган дава и другата – японската – перспектива. Подходът, който ни показва крехкостта на човека и от двете страни, моралната относителност, дълбоките основания, е задължителен за високата проза. И все пак не ми даваше покой въпросът (до който също не стигнахме) дали можем да си позволим фразата „въпрос на гледна точка е“ във времена, когато сме изправени пред невъзможността, поне на ниво политици, недвусмислено, черно на бяло да посочим агресора в нашата съвременна война. Колко в дълбоко личното трябва да се пренесем, за да изпитаме еднаква емпатия към загубите и от едната, и от другата страна?
Повърхностна и неинтелигентна ли е категоричната морална оценка?
Поставяйки ги в контекст, Фланаган ни кара да изпитаме състрадание дори към най-свирепите поданици на японския император (действащи според кодекса бушидо), ала сам признава, че изкуплението и отмъщението не могат да възстановят справедливостта и равновесието. Той не успя да отговори на въпроса ми дали изобщо вярва в някакъв баланс, в някаква изначална, логична справедливост на съществуването?
„Тесният път към далечния север“ е роман за смъртта на духа след оцеляването на плътта. Едновременно брутален и лиричен, романът е словесен паметник на хилядите останали завинаги в калта на далечния север по пътя към една надмогваща човека идеология. Препоръчвам да прочетете тази своеобразна класика заедно с последния издаден у нас роман на Фланаган „Въпрос 7“, както и да обърнете внимание на „Живо море от сънища наяве“, който пък дава контрапункт от различен, болезнено актуален съвременен ъгъл (екологичен и климатичен) на целия смисъл на опростенчески героизираното в толкова много литературни произведения човешко оцеляване.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. За нея медията „Тоест“ е отличена с Националната награда „Христо Г. Данов“ (2025) за принос в представянето на българската книга.
Рубриката е част от партньорската програма Читателски клуб „Тоест“, благодарение на която активните дарители на „Тоест“ получават 20% отстъпка от коричната цена на всички книги на включените издателства. Изборът на заглавия обаче е единствено на авторите Стефан Иванов, Севда Семер и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как да се разходите с тях в книжарницата.
[$] LWN.net Weekly Edition for November 19, 2026
Post Syndicated from jzb original https://lwn.net/Articles/1107147/
Inside this week’s LWN.net Weekly Edition:
- Front: C++26 standard; Buildroot; Faster futexes; Zellij; Julia language.
- Briefs: Glasswing; NGINX RCE; XRAID; Manjaro nonprofit; 30 years of curl; MATE; Redict deprecated; Rust 1.100; Quotes; …
- Announcements: Newsletters, conferences, security updates, patches, and more.
Introducing automatic version upgrades for AWS Glue jobs
Post Syndicated from Keerthi Chadalavada original https://aws.amazon.com/blogs/big-data/introducing-automatic-version-upgrades-for-aws-glue-jobs/
Many organizations run their Apache Spark pipelines on AWS Glue and each new AWS Glue release means another round of version upgrades. New versions bring better performance and new features, but upgrading takes work. For every job, an engineer reviews breaking changes across Spark, Python, and libraries, then runs the job on the new version and confirms that it produces the same results. Many jobs turn out to need no changes, but the team learns that only after doing the work. Across hundreds of jobs, upgrading becomes a project that keeps coming back, so many jobs stay on older versions.
Today, we’re announcing automatic version upgrades for AWS Glue jobs (auto upgrade). When you set a job’s version to auto, AWS Glue analyzes the job, asks for your approval, and moves the job to the latest stable version. Instead of planning, testing, and tracking each upgrade, your team reviews and approves it.
In this post, you learn how auto upgrade works and how to:
- Turn on auto upgrade for a job and approve the upgrade in the AWS Glue console.
- Use an AI agent to assess a fleet of jobs, turn on auto upgrade with email notifications, approve the upgrades, and check the results.
How auto upgrade works
Set a job’s GlueVersion to auto to turn on auto-upgrade. The job keeps running as usual on its current version while AWS Glue checks the job for known breaking changes. AWS Glue doesn’t modify your script. When AWS Glue determines that the job needs no code changes, AWS Glue sends you an eligibility summary with the compatibility results for application code, configuration, and dependencies, and requests your approval. The job stays on its current version until you approve. After you approve, AWS Glue runs the job on the new version and checks the upgraded runs against the job’s earlier runs. AWS Glue then sends you an auto upgrade evaluation summary with the results for correctness, performance, and cost. If the upgraded runs pass the checks, AWS Glue completes the upgrade, and all subsequent runs use the new version. If an upgraded run fails, AWS Glue retries the run on the previous version, so your pipeline keeps running, and then reverts the job. For details, see How an auto upgrade evaluation works in the AWS Glue User Guide.
For jobs whose code must change, use generative AI upgrades for Apache Spark in AWS Glue.
Prerequisites
To follow along, you need the following:
- A user or role with the IAM permissions for auto upgrade.
- One or more AWS Glue jobs that meet the following requirements:
- The job is a Spark ETL job (
glueetl) on AWS Glue 2.0 or later. - The job’s
MaxRetriesparameter is set to 1 or higher, and job run queuing is turned off. - The job is safe to retry.
- The job is a Spark ETL job (
For the AI agent walkthrough, you also need the following:
- An AI agent that supports skills and MCP servers, such as Kiro or Claude Code, with the managing-glue-jobs skill from the AWS Glue samples repository on GitHub.
- The latest version of the AWS Command Line Interface (AWS CLI) version 2.
- The
spark-upgradeMCP server from Amazon SageMaker Unified Studio, which runs the compatibility assessment. To connect the server, see the skill’s README. - For email notifications, the Amazon Simple Notification Service (Amazon SNS) and Amazon EventBridge permissions in the skill’s permissions.md file.
To install the skill, copy the skill folder into your agent’s skills folder.
Walkthrough: Use auto upgrade in the AWS Glue console
In the AWS Glue console, you turn on auto upgrade and approve the upgrade one job at a time.
Create a job with auto upgrade
- Open the AWS Glue console, and in the navigation pane, choose ETL jobs.
- Create a Spark job, and then choose the Job details tab.
- For AWS Glue version, choose Auto.
- For Number of retries, enter 1 or higher.
- Choose Save.
AWS Glue runs a new auto job on the latest stable version and evaluates the job when the next version is released.
Change an existing job to auto upgrade
- In the AWS Glue console, in the navigation pane, choose ETL jobs.
- Choose the job, and then choose the Job details tab.
- For AWS Glue version, choose Auto, and for Number of retries, enter 1 or higher.
- Choose Save.
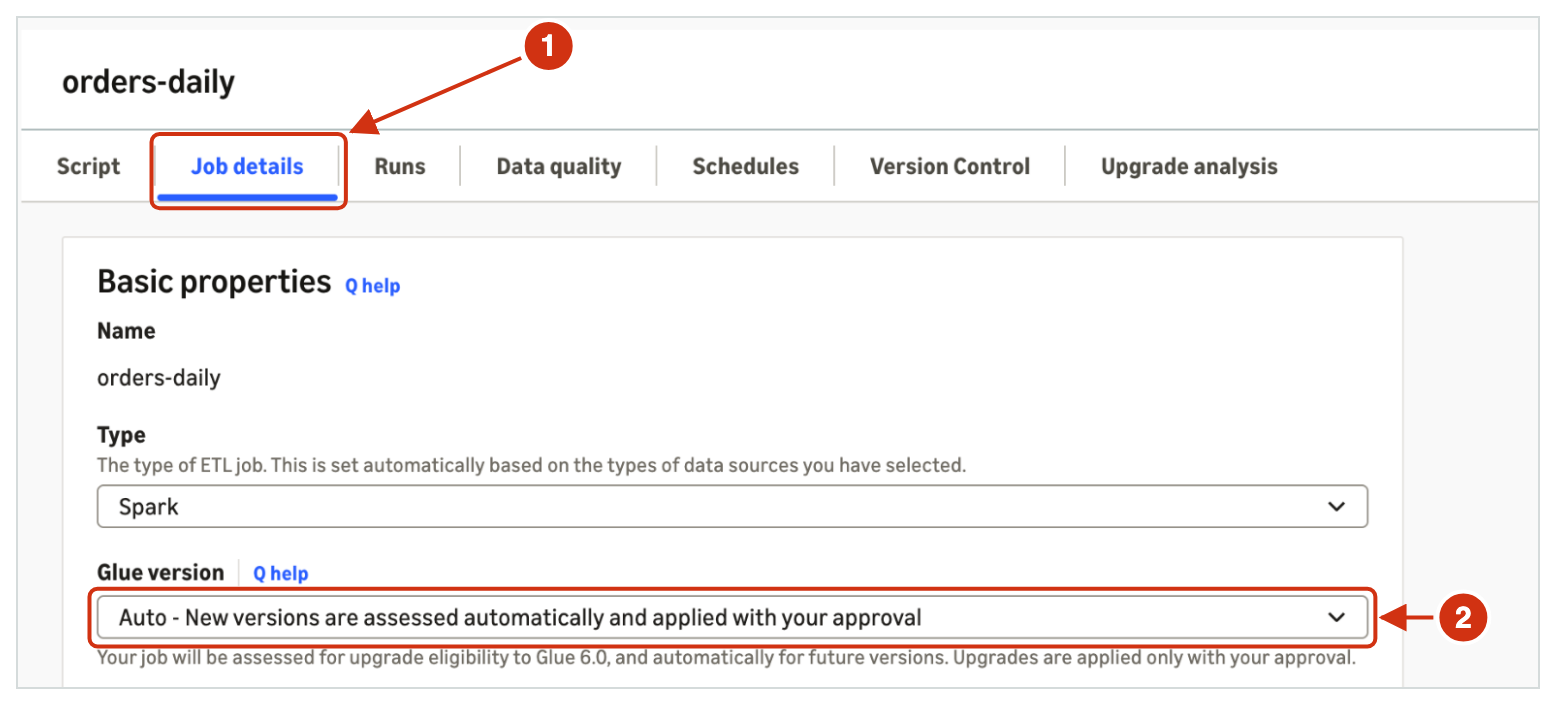
Figure 1: The Job details tab for orders-daily, with AWS Glue version set to Auto
Approve or decline the upgrade
When AWS Glue finishes the compatibility checks and finds no blocking issues, the job waits for your approval.
- Choose the job, and then choose the Upgrade analysis tab. The analysis status shows Waiting for consent.
- In the Upgrade consent required banner, choose eligibility summary, and review the summary.
- Choose Approve to upgrade the job, or choose Decline to keep the job on its current version.
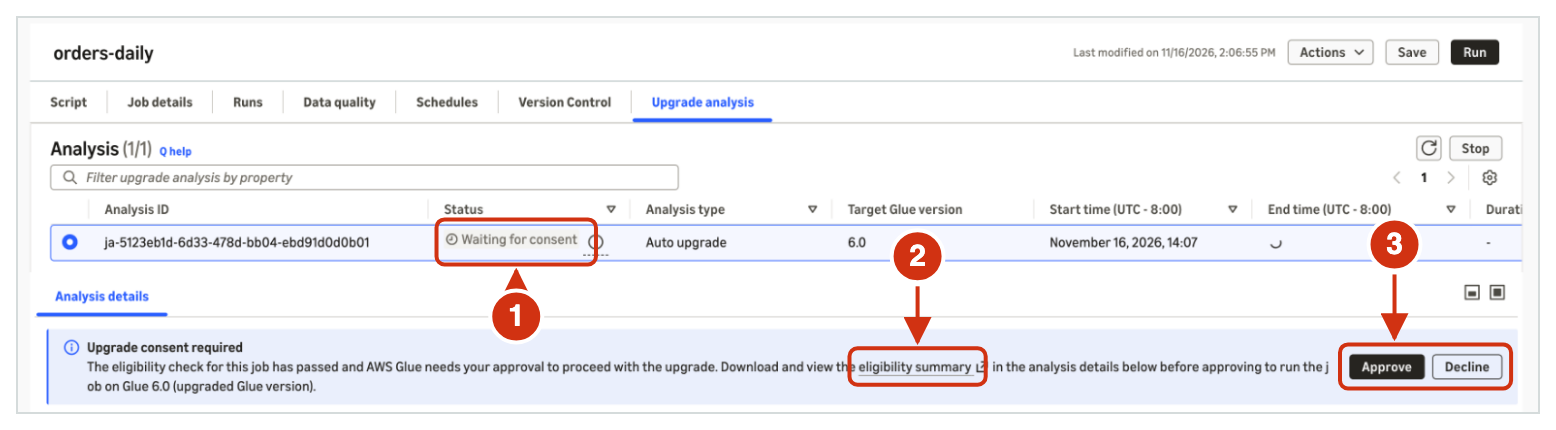
Figure 2: The Upgrade analysis tab for orders-daily, waiting for your approval
The eligibility summary shows the job, the AWS Glue versions, and the compatibility results.
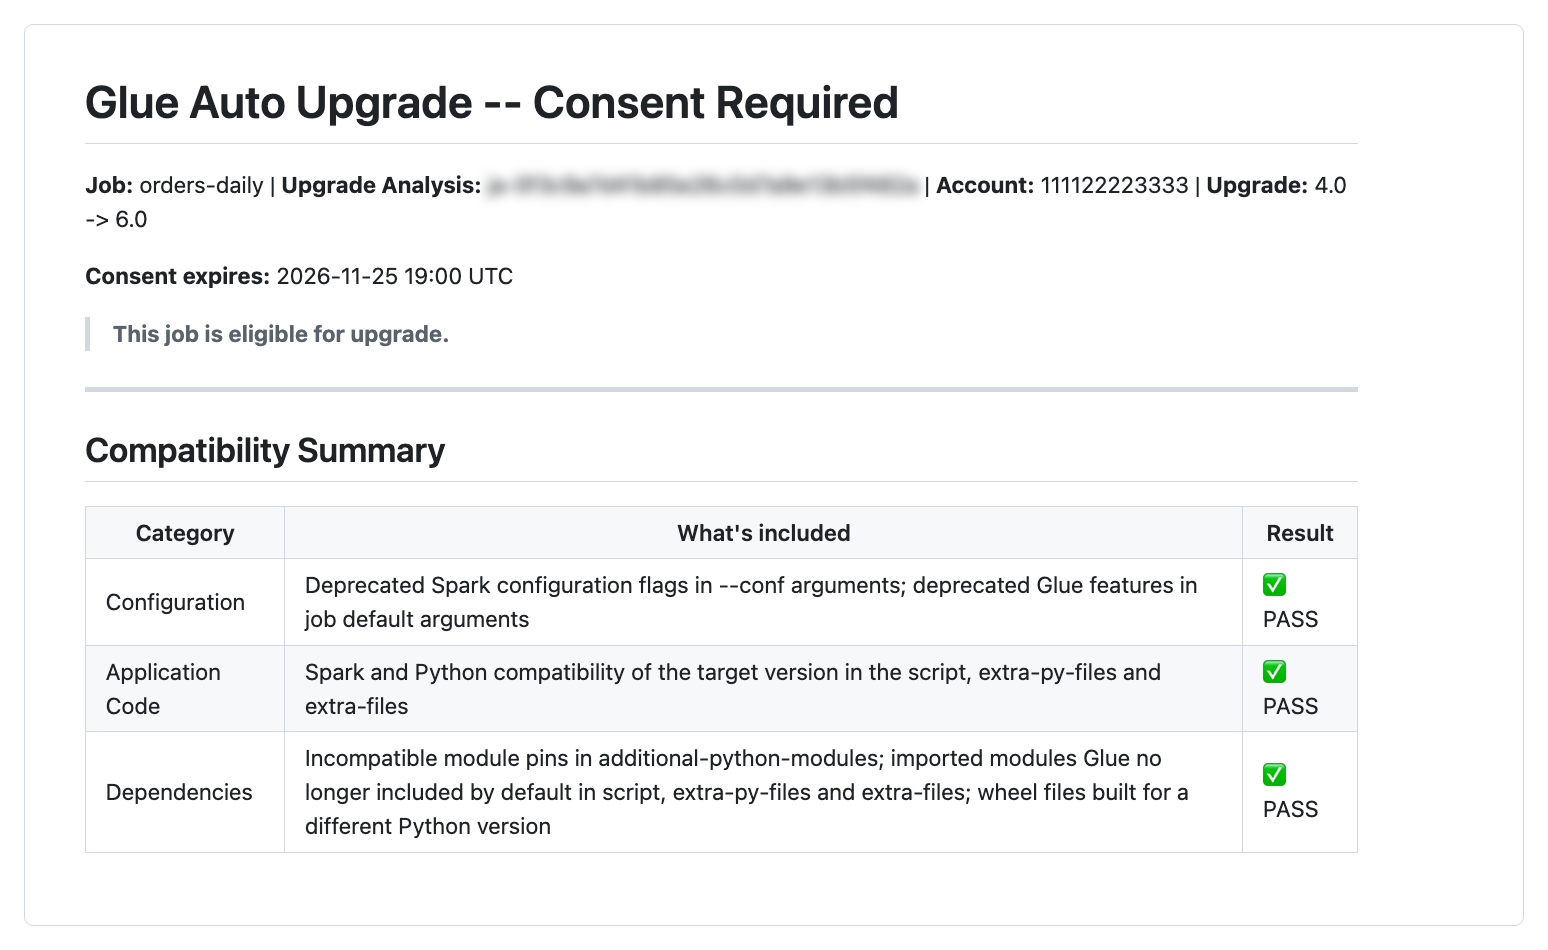
Figure 3: The eligibility summary for orders-daily
Check the result
After the evaluation ends, the Upgrade analysis tab shows the auto upgrade evaluation summary. The summary shows the result for performance, correctness, and cost, with the expected range and each upgraded run’s value for every check.
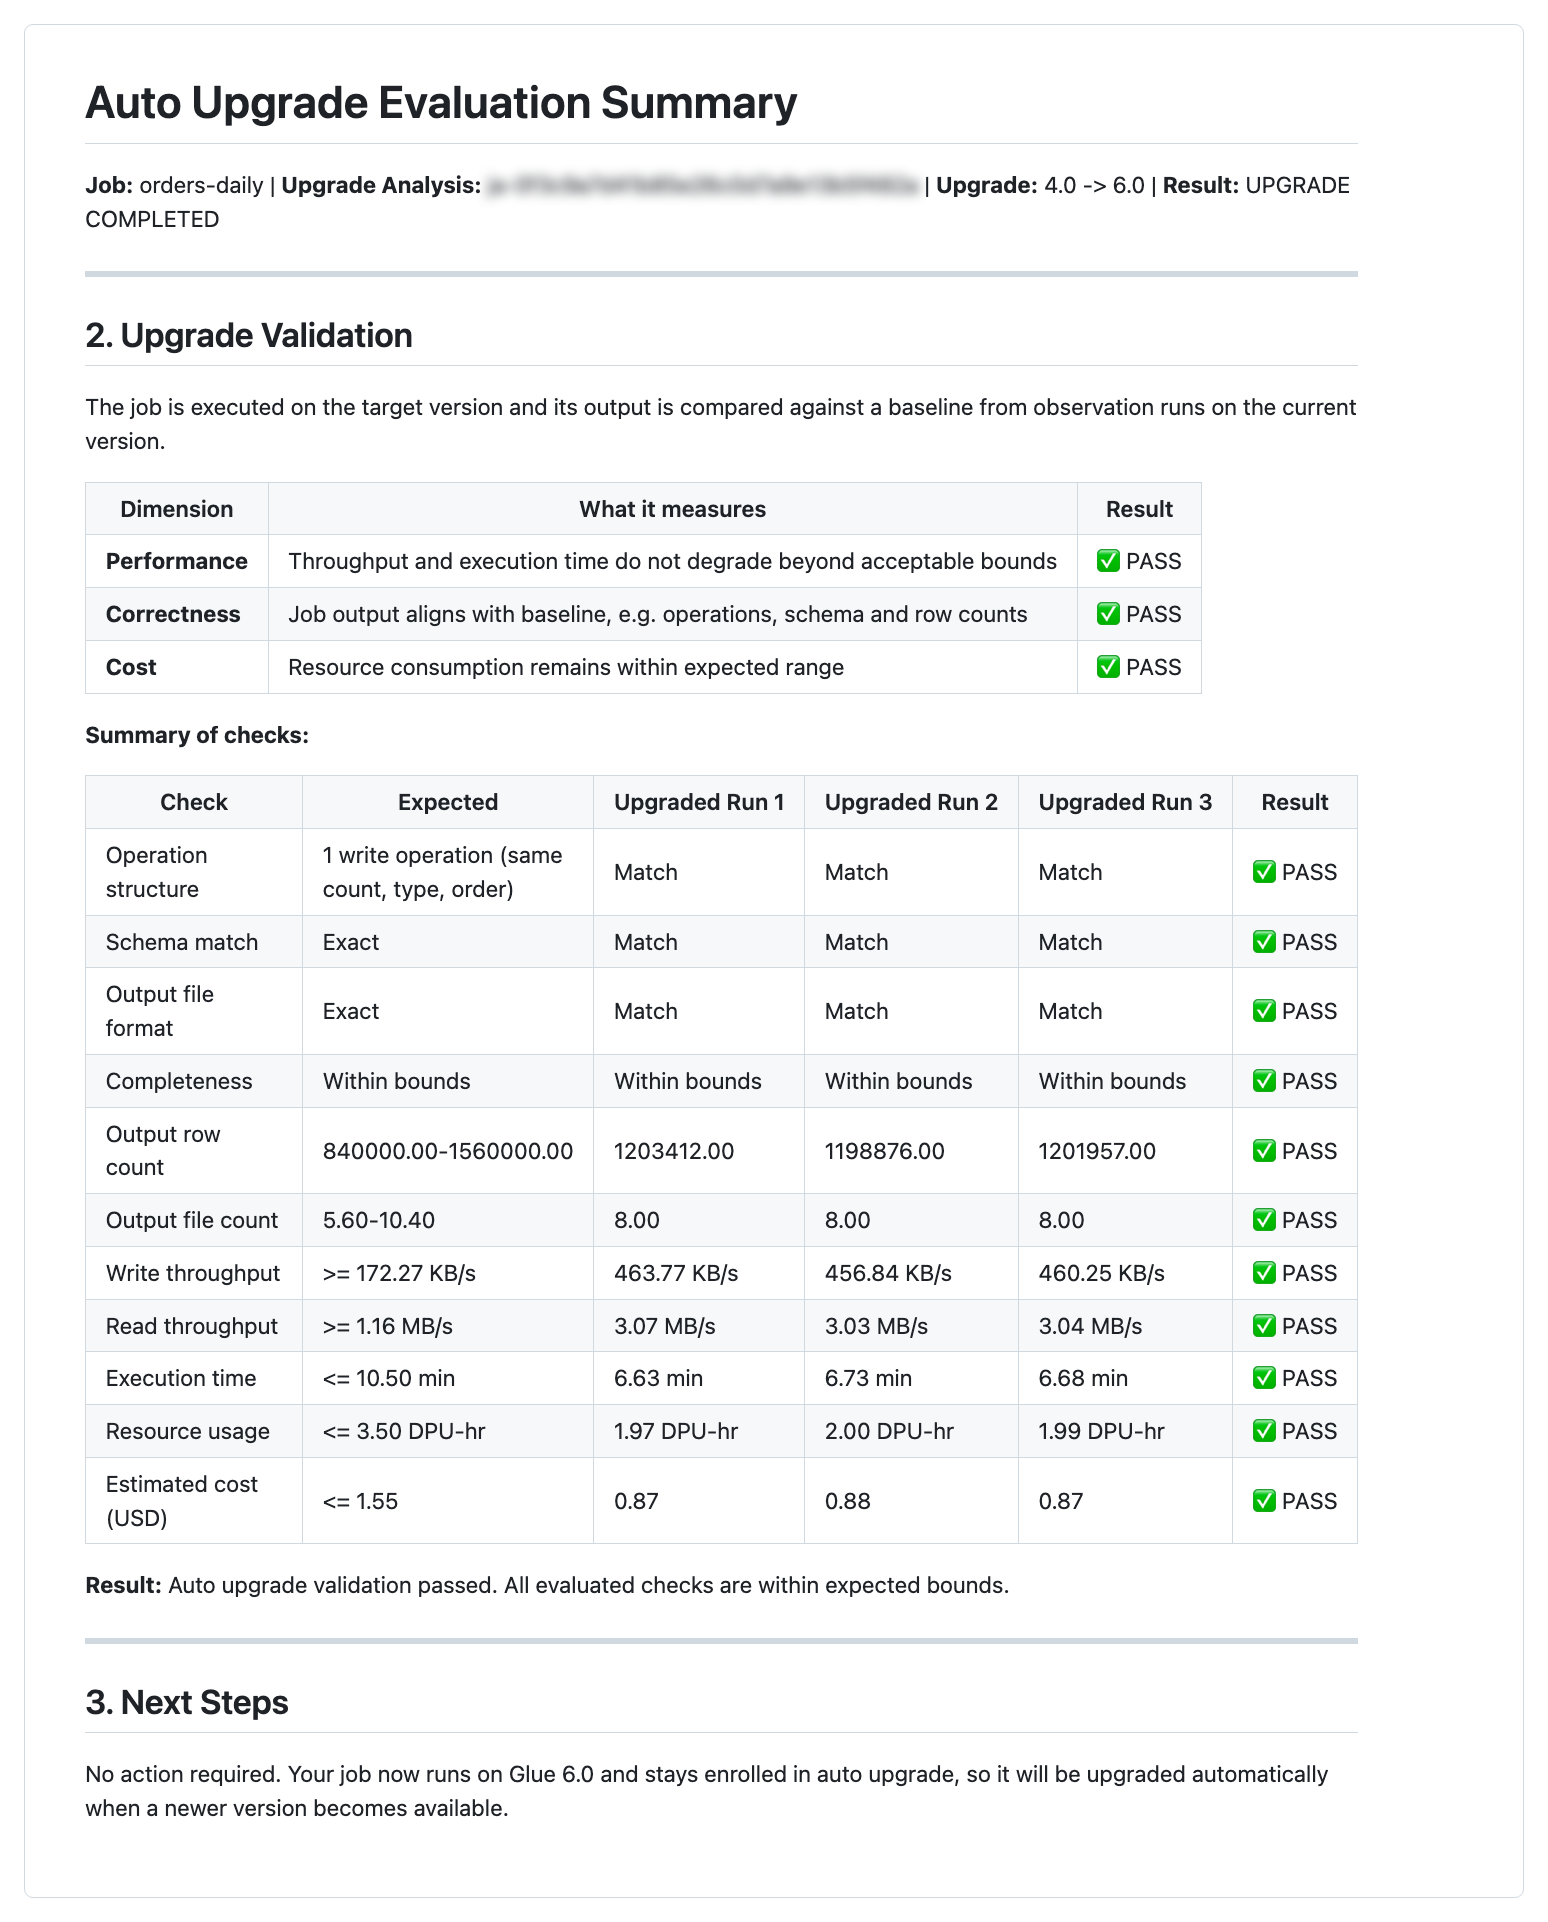
Figure 4: The auto upgrade evaluation summary for orders-daily
Walkthrough: Upgrade a fleet of jobs with an AI agent
When you manage many jobs, an AI agent with the managing-glue-jobs skill assesses, turns on, and approves auto upgrade across your jobs from a few prompts. The agent shows each change and asks for your confirmation before it makes the change.
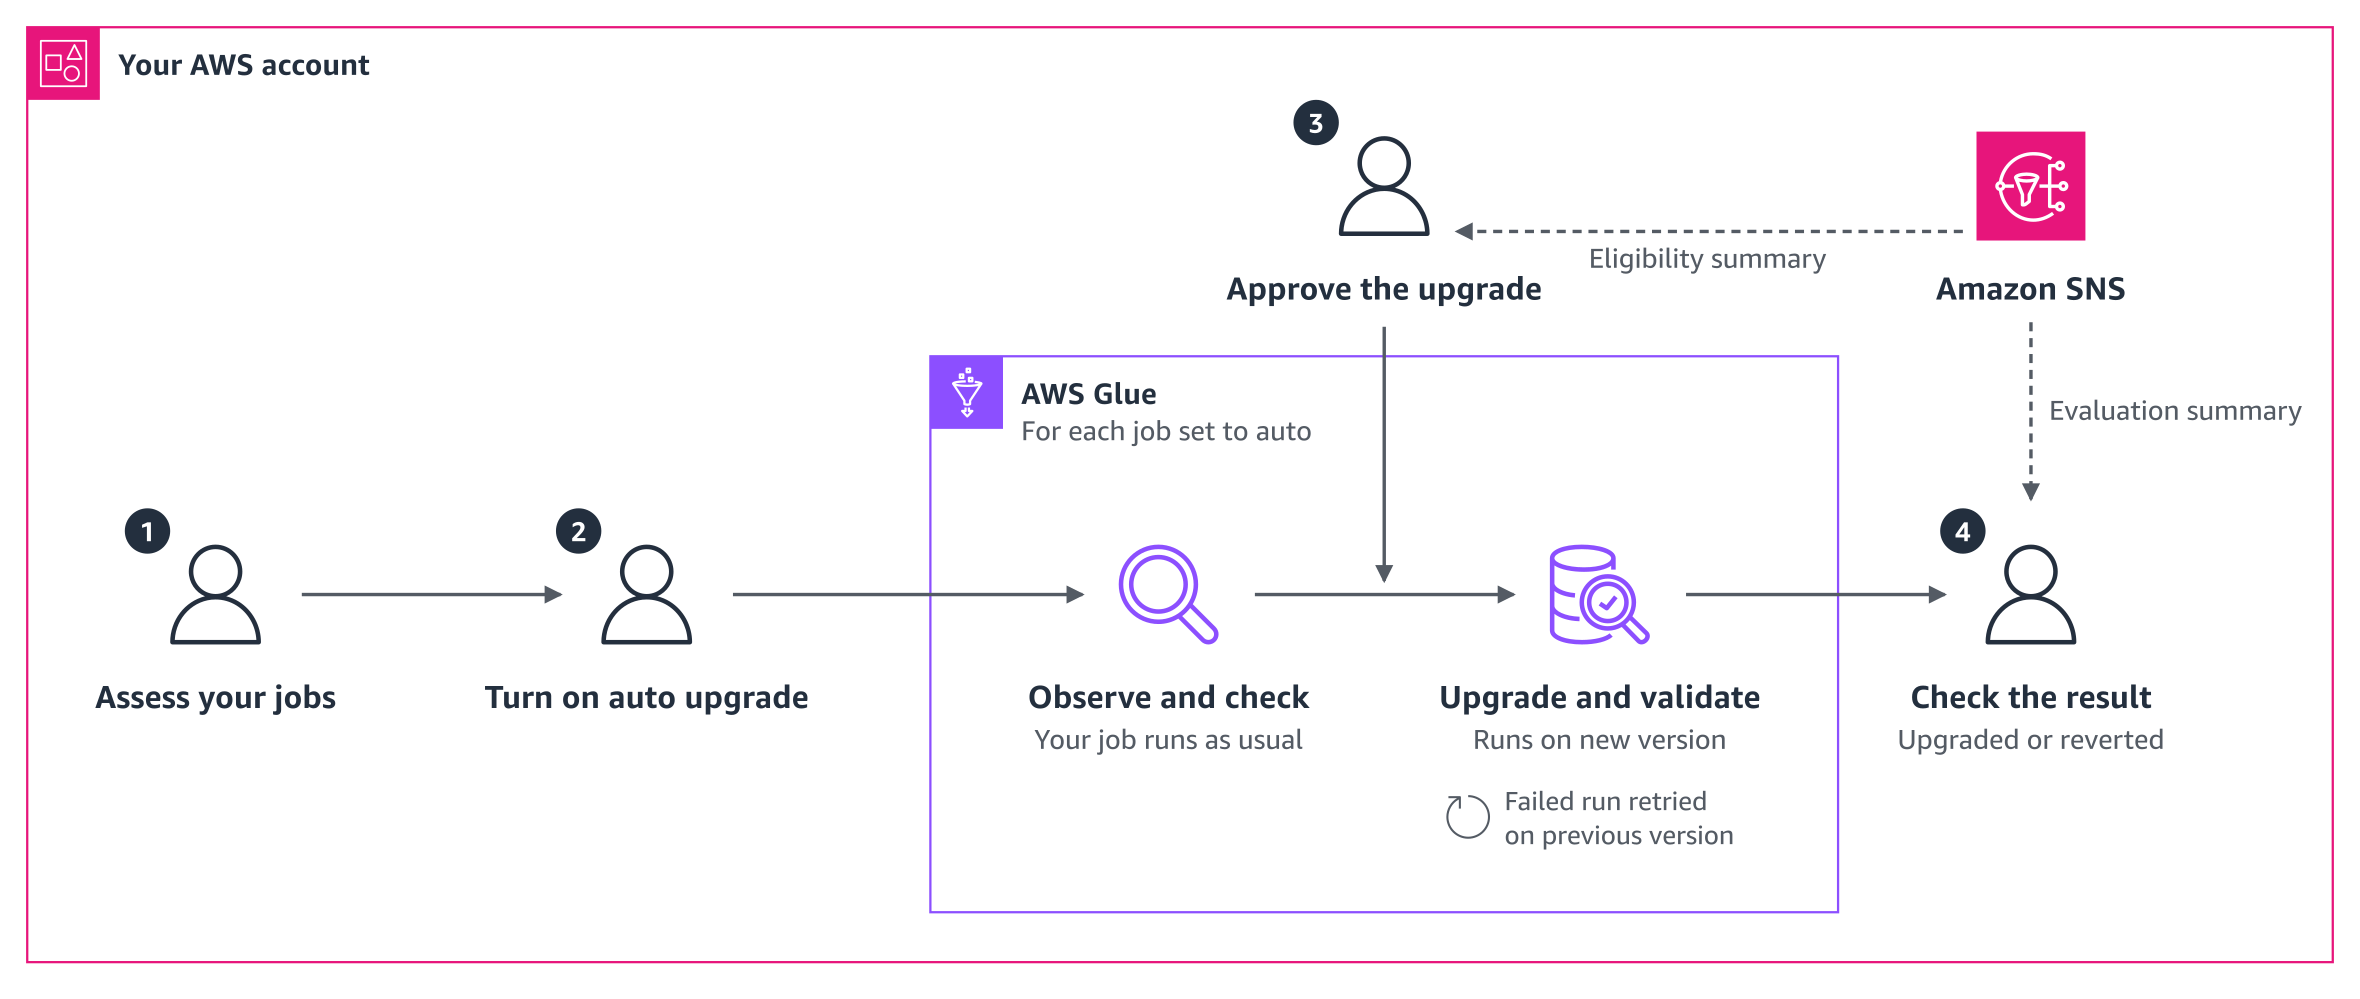
Figure 5: The auto upgrade journey for existing jobs
In this walkthrough, you assess your jobs, turn on auto upgrade, approve the upgrade, and check the result. Between these steps, AWS Glue observes and checks each job, and then upgrades and validates the job. Amazon SNS emails you the eligibility summary and the evaluation summary. The steps that follow match the numbers in Figure 5.
A data team runs three Spark ETL jobs in the US West (Oregon) Region and they want to use AWS Glue version 6.0. The jobs orders-daily and clickstream-agg run on AWS Glue 4.0 and write to Amazon Simple Storage Service (Amazon S3). The job customer-profiles runs on AWS Glue 3.0.
Step 1: Assess your jobs
Ask the agent which of your jobs can use auto upgrade. The assessment does not change anything in your environment, so it’s safe to try first. The agent checks each job against the requirements and runs a compatibility assessment. The agent then lists the jobs that can move to AWS Glue 6.0 and asks you to confirm that each job is safe to retry.
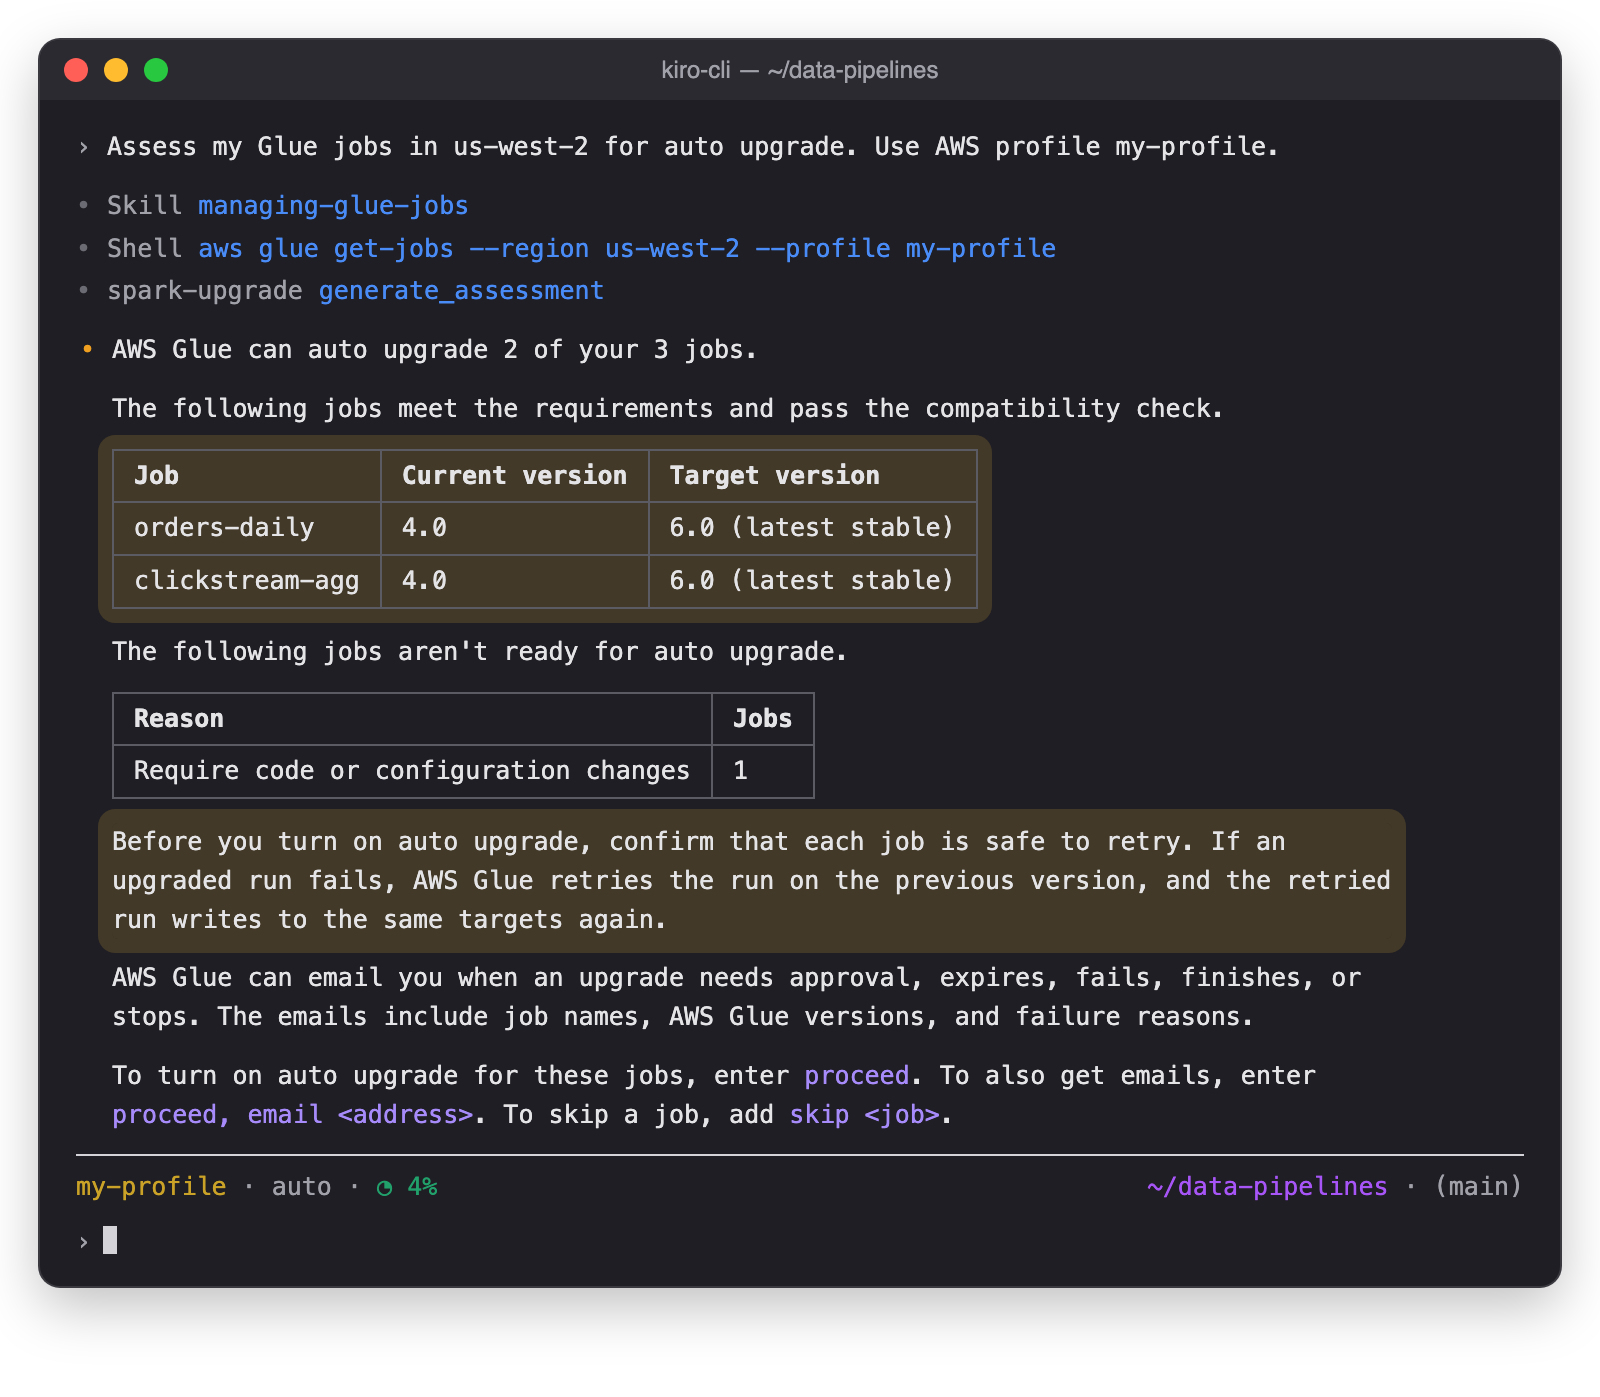
Figure 6: The agent assesses the jobs
To see which job isn’t ready and why, ask the agent. The agent names the setting that blocks the upgrade and the fix.
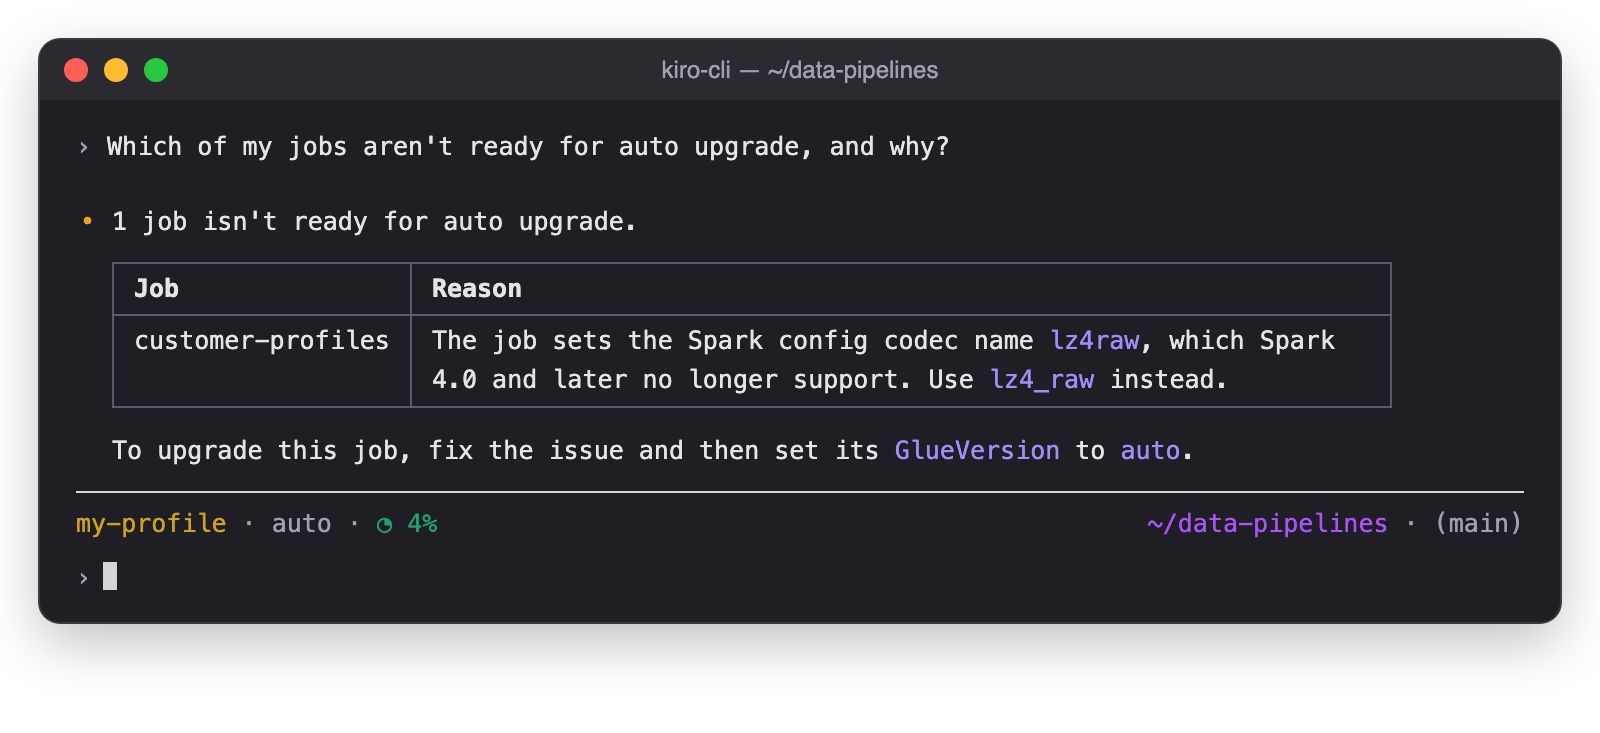
Figure 7: The agent explains why a job isn’t ready
After you update the setting, set the AWS Glue job customer-profiles to auto. For jobs whose code must change, use generative AI upgrades for Apache Spark in AWS Glue.
Step 2: Turn on auto upgrade and set up email notifications
Ask the agent to turn on auto upgrade and set up email notifications in one prompt. The agent sets up the email notifications and sets GlueVersion to auto for each job. The jobs keep running on AWS Glue 4.0 until you approve an upgrade. To get the email notifications, confirm the subscription as the reply describes.
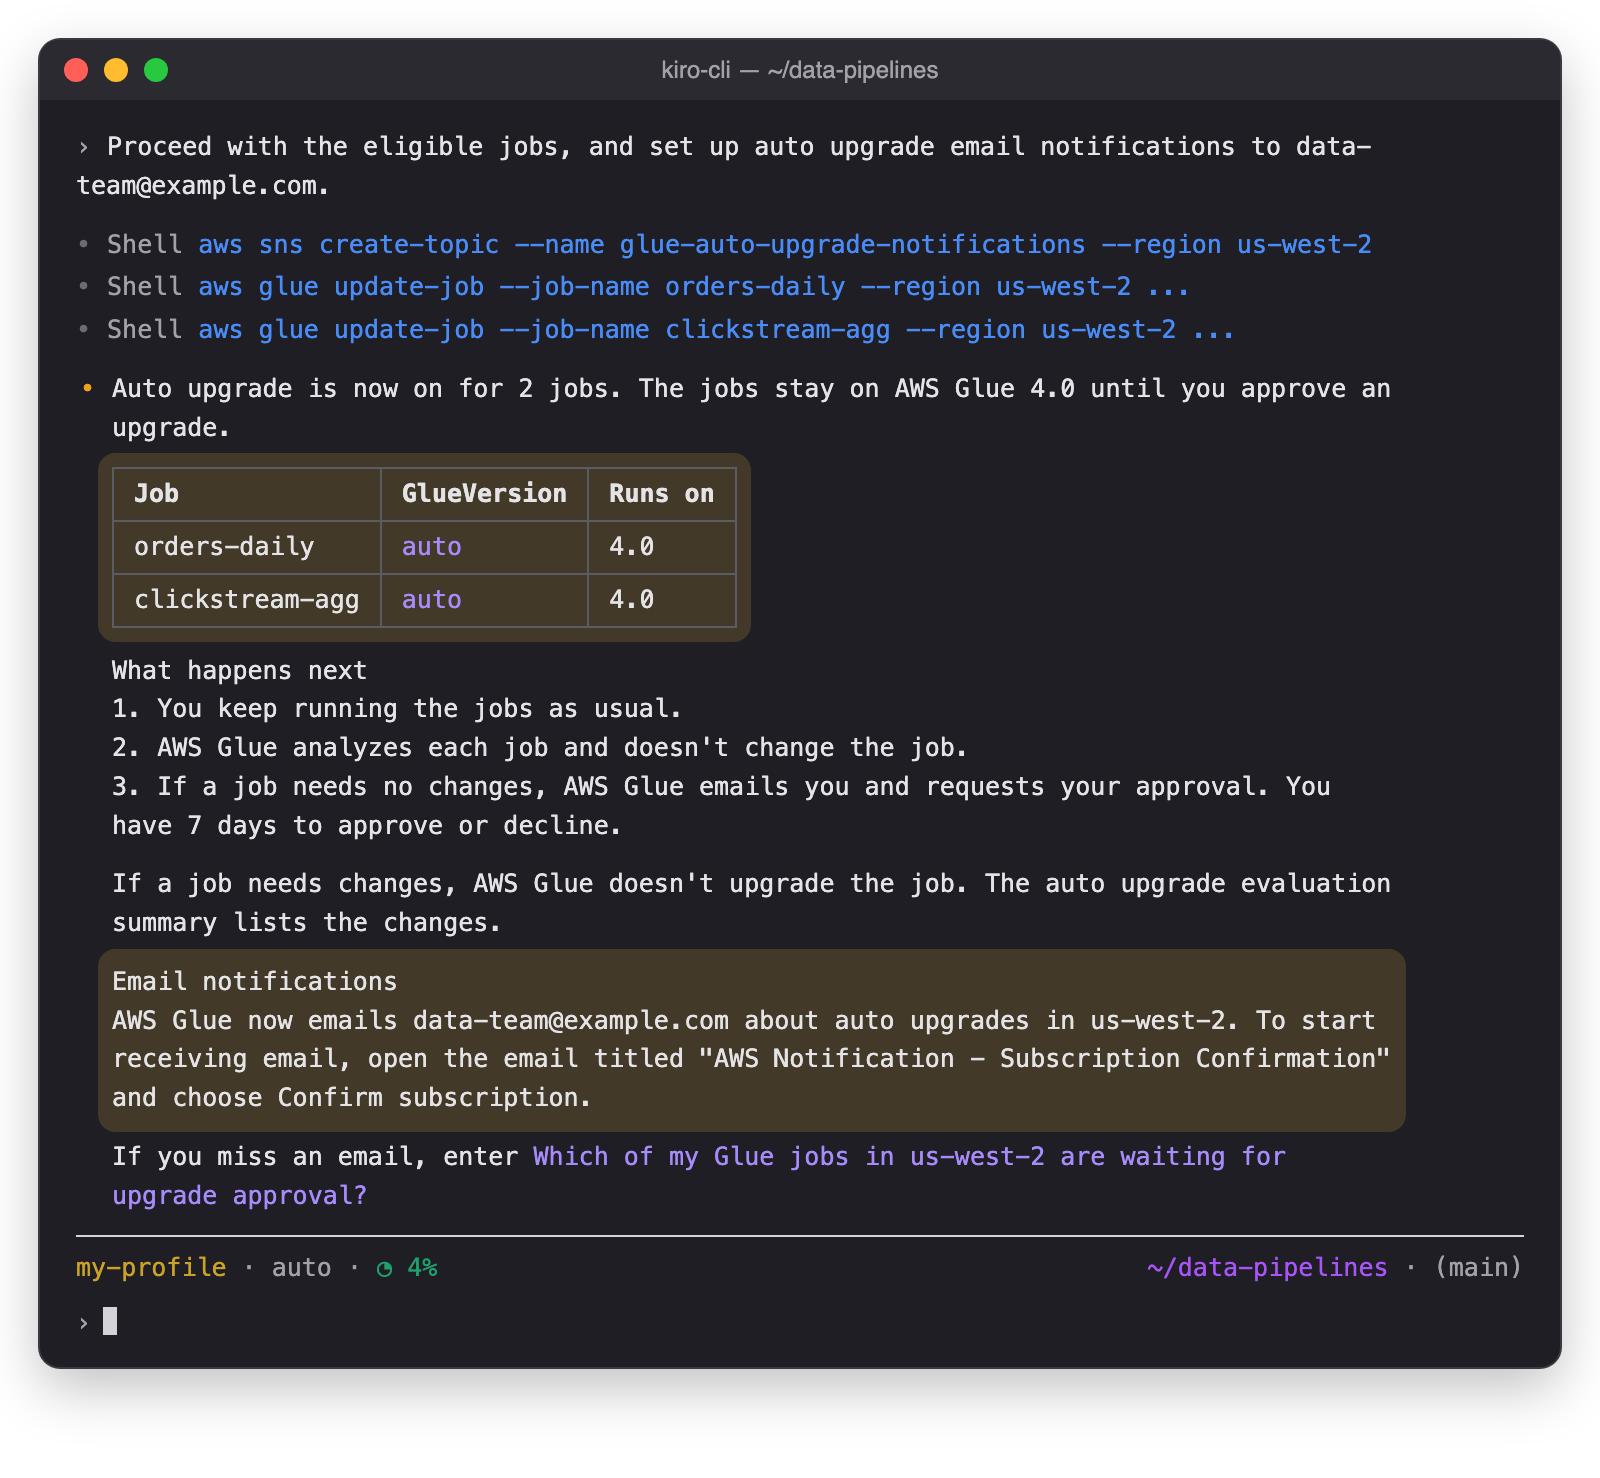
Figure 8: The agent turns on auto upgrade and sets up email notifications
Step 3: Review and approve the upgrade
AWS Glue observes and checks each job in the background, and then you review and approve the upgrade.
Step 3a: AWS Glue observes and checks
You keep running the jobs on their usual schedule. In the background, AWS Glue observes the runs and analyzes each job without changing it. How long this takes depends on how often each job runs.
When a job is ready, AWS Glue emails you and requests your approval. The email names the job and the AWS Glue versions, and links to the job in the AWS Glue console. You have seven days to approve or decline.
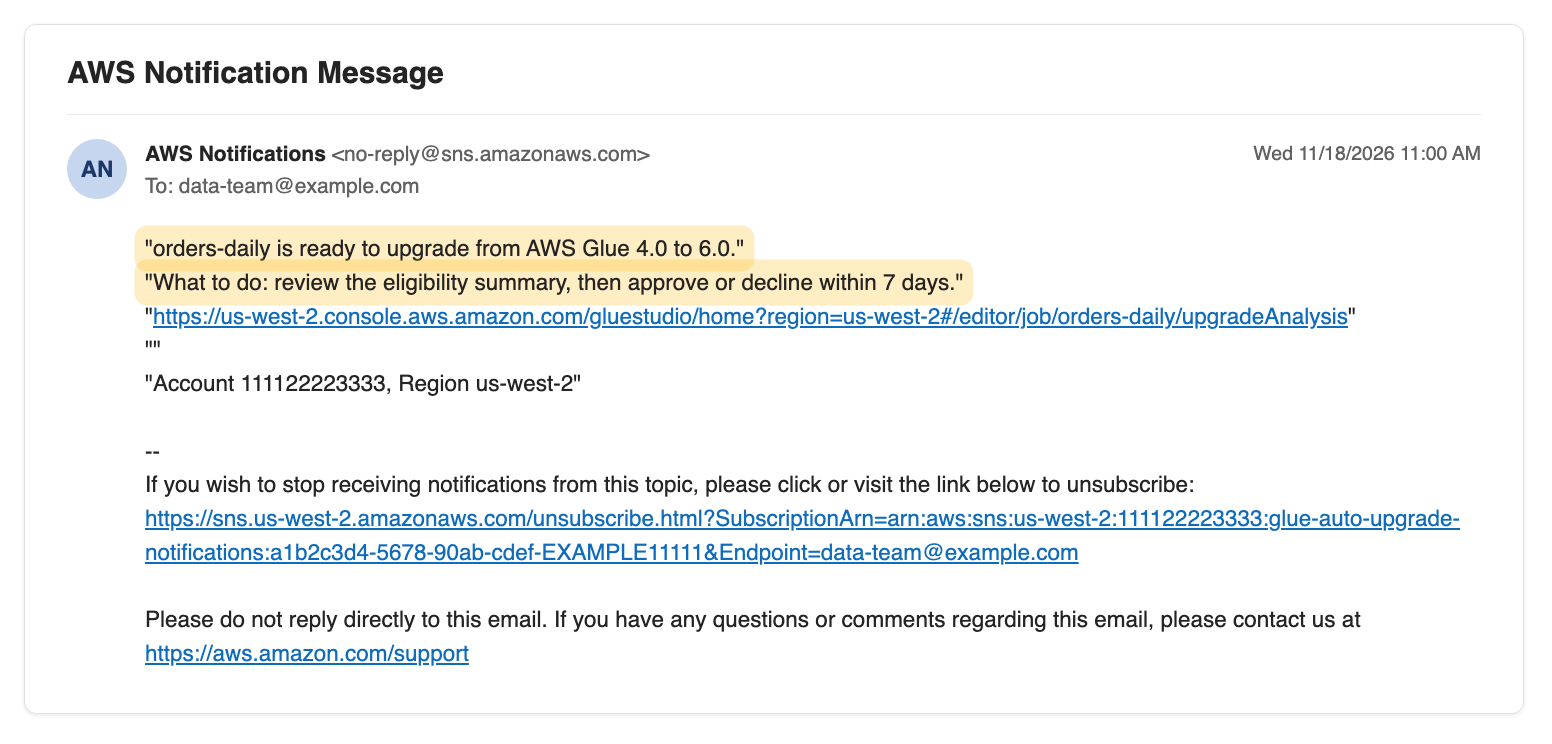
Figure 9: The approval request email
Step 3b: Review and approve the upgrade
Ask the agent which upgrades are waiting. The agent reads the eligibility summary of each job, and then shows the jobs, their write paths, and what to confirm before you approve.
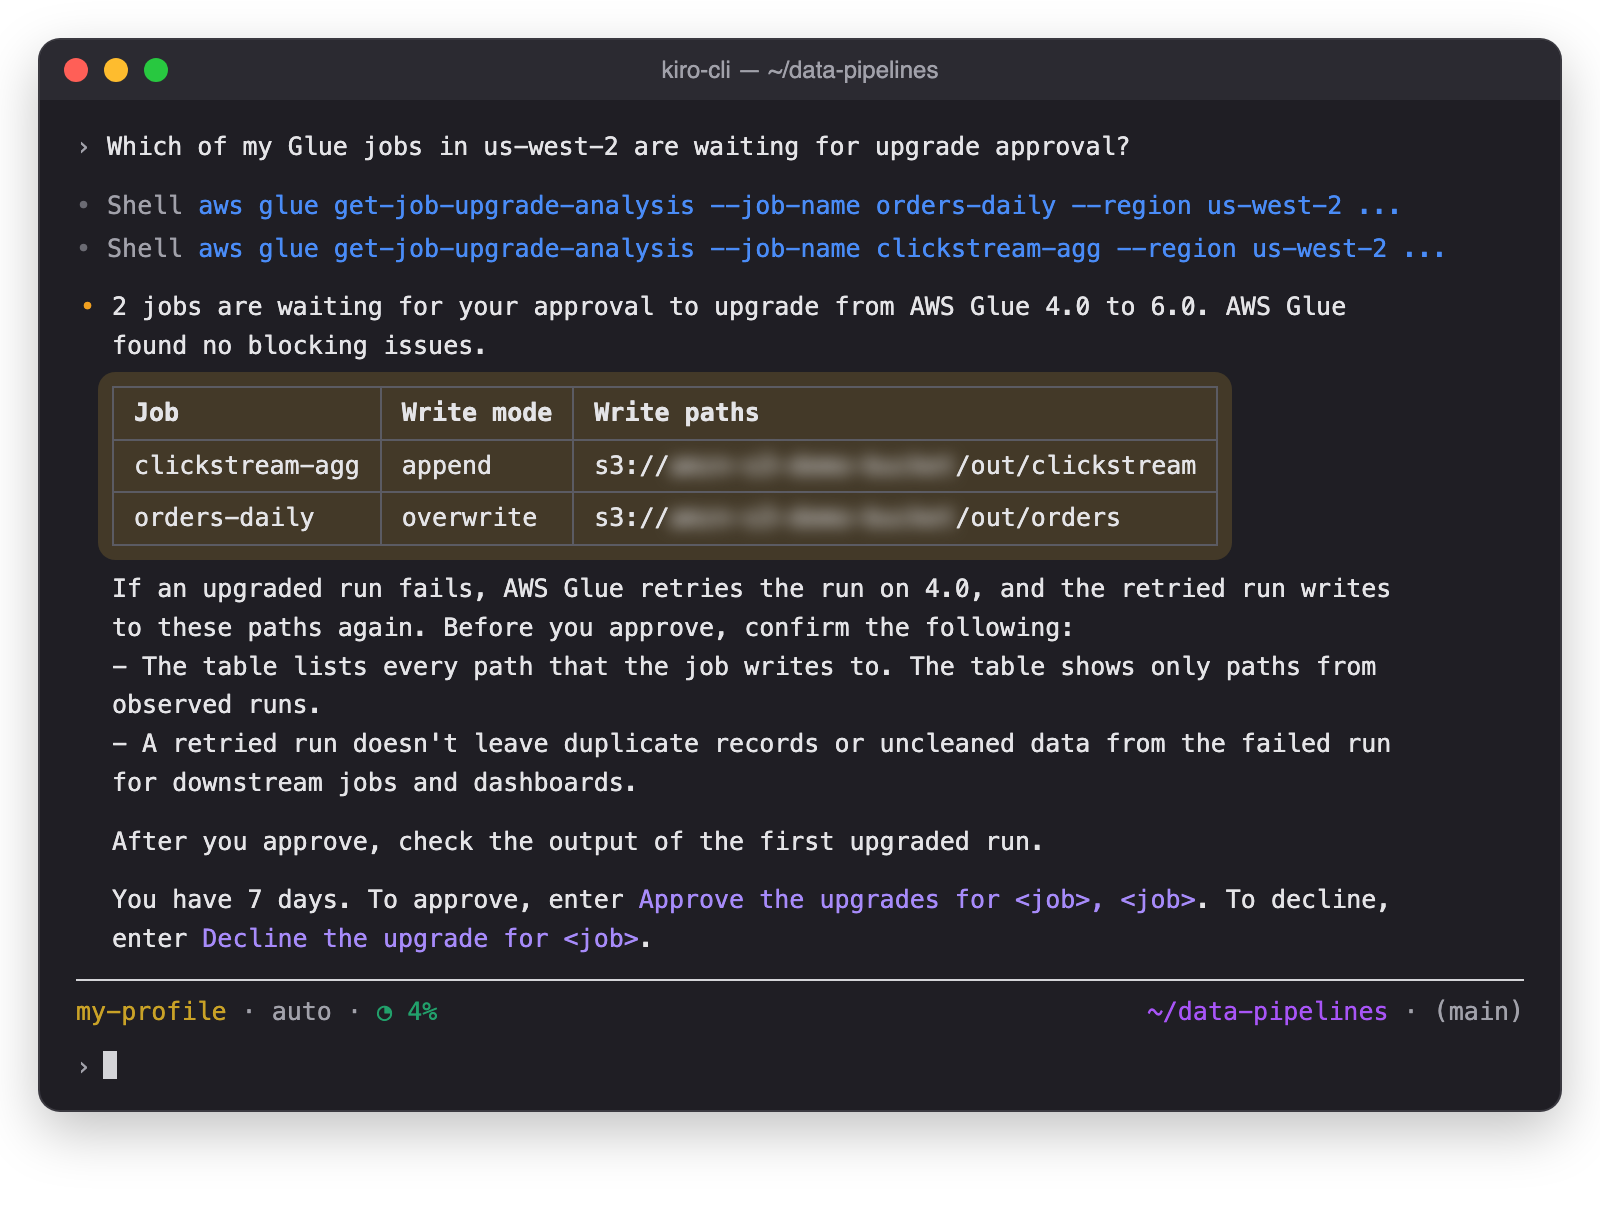
Figure 10: The agent shows the upgrades that wait for your approval
Before you approve, confirm that the reply lists every path that each job writes to. Then approve the jobs in one prompt, and name each job that you approve.
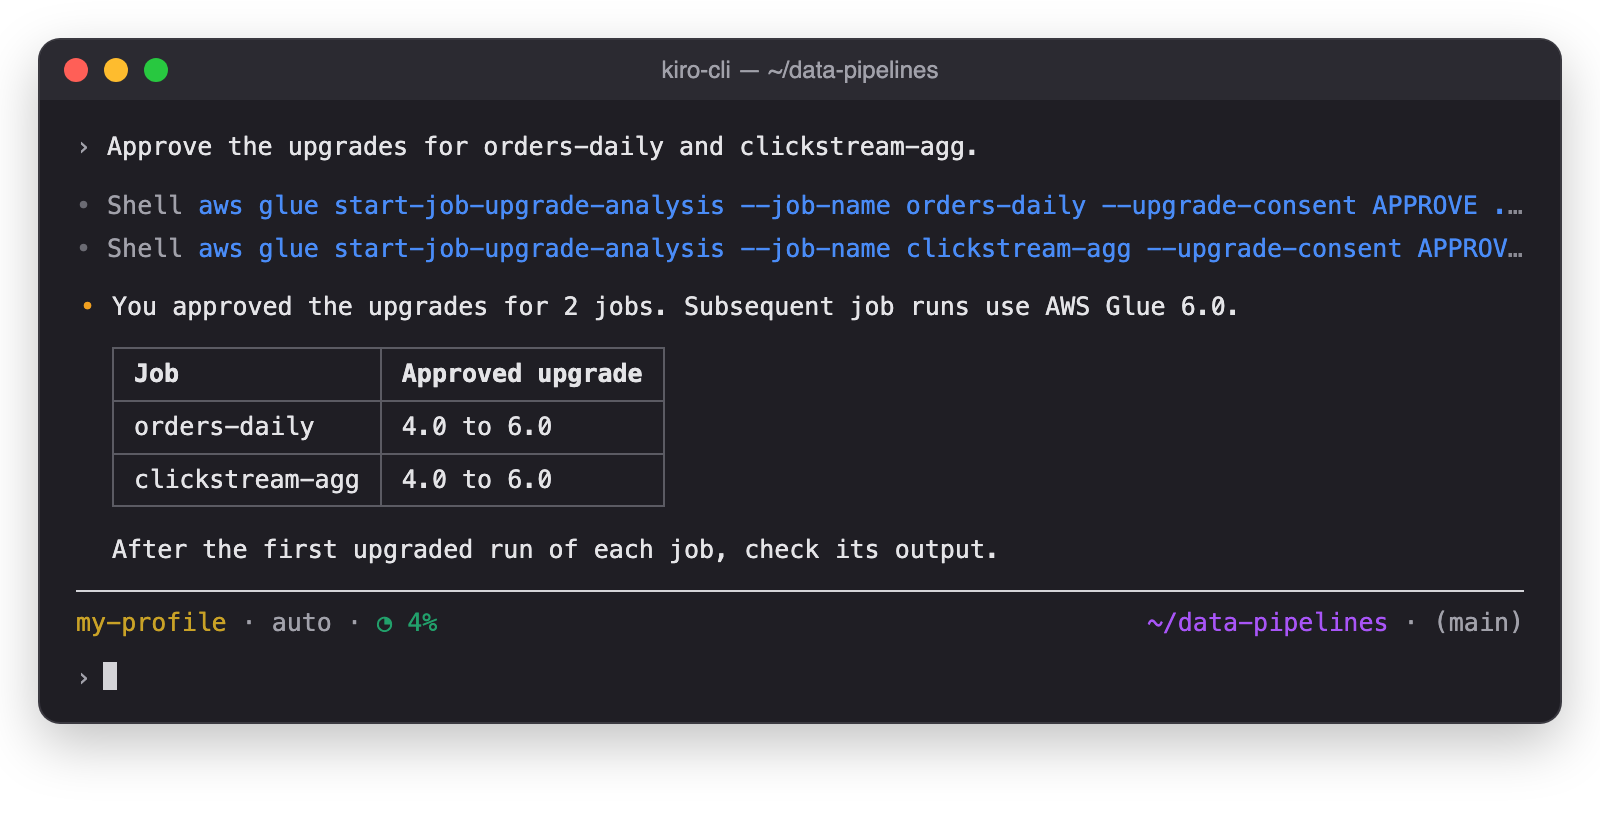
Figure 11: The agent approves the named jobs
The agent approves only the jobs that you name, and only jobs from the review that it showed you.
Step 4: Check the result
AWS Glue upgrades and validates each job, and then you check the result.
Step 4a: AWS Glue upgrades and validates
After you approve, subsequent runs of each job use AWS Glue 6.0, and AWS Glue validates the upgraded runs. If an upgraded run fails, AWS Glue retries the run on AWS Glue 4.0 and reverts the job. You don’t need to act in this step.
Step 4b: Check the result
When the evaluation of a job ends, AWS Glue emails you the result. Ask the agent for the result of orders-daily. The agent shows the result of each validation check.
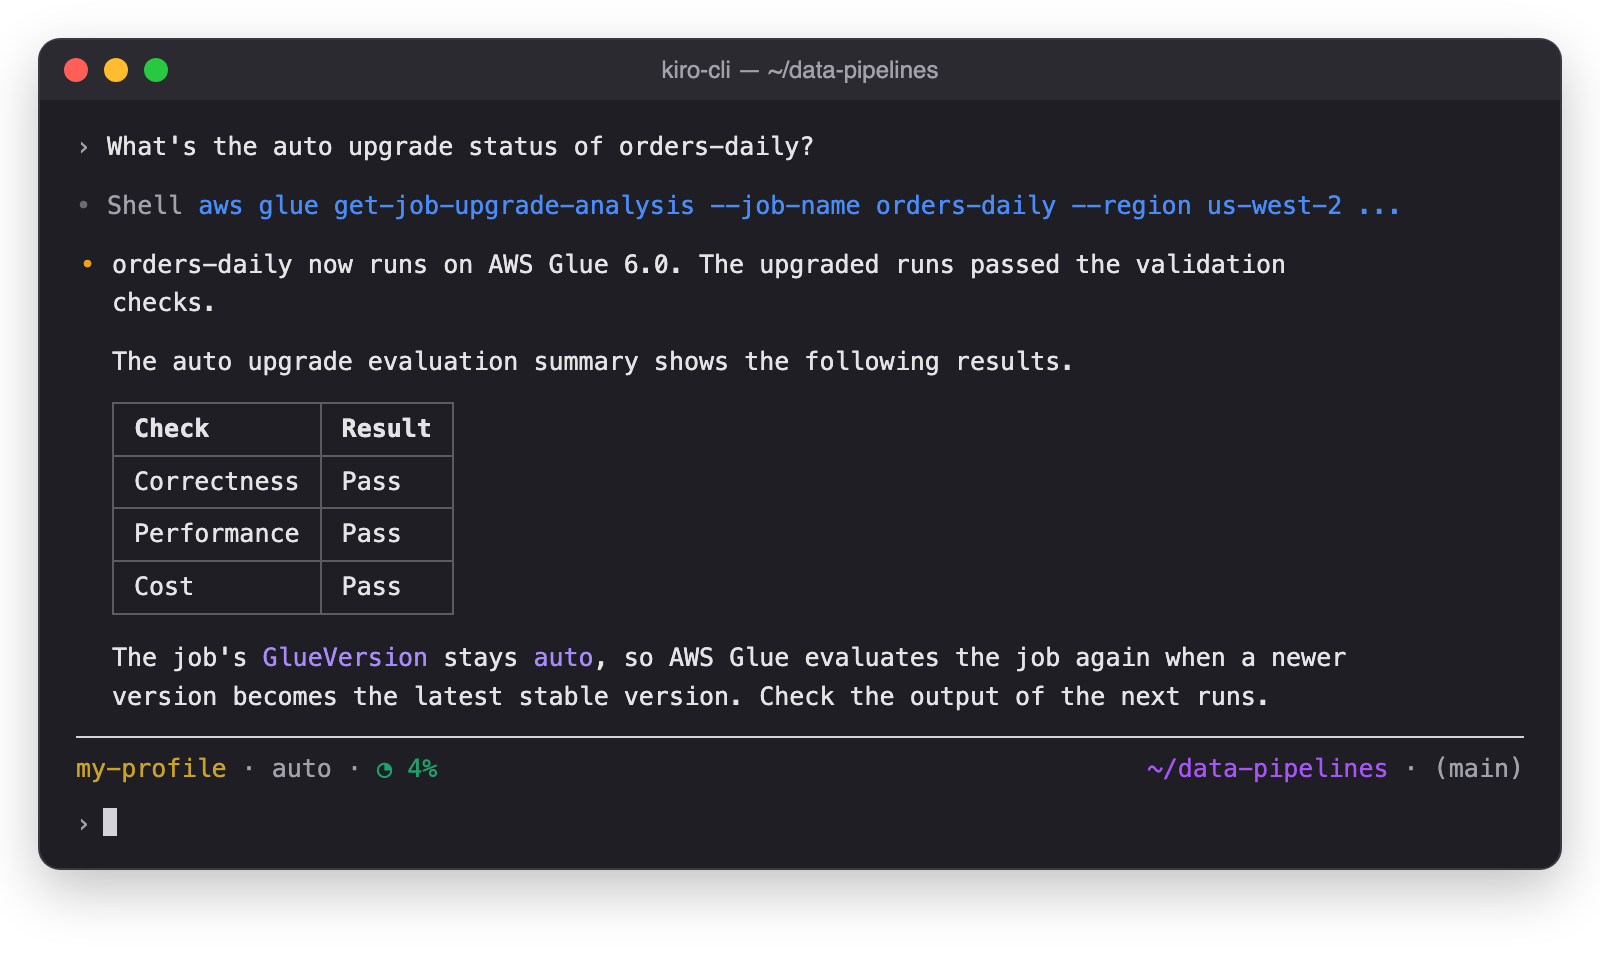
Figure 12: The agent shows the result for orders-daily
Ask the agent about the other job. The agent shows the check that failed and suggests a fix.
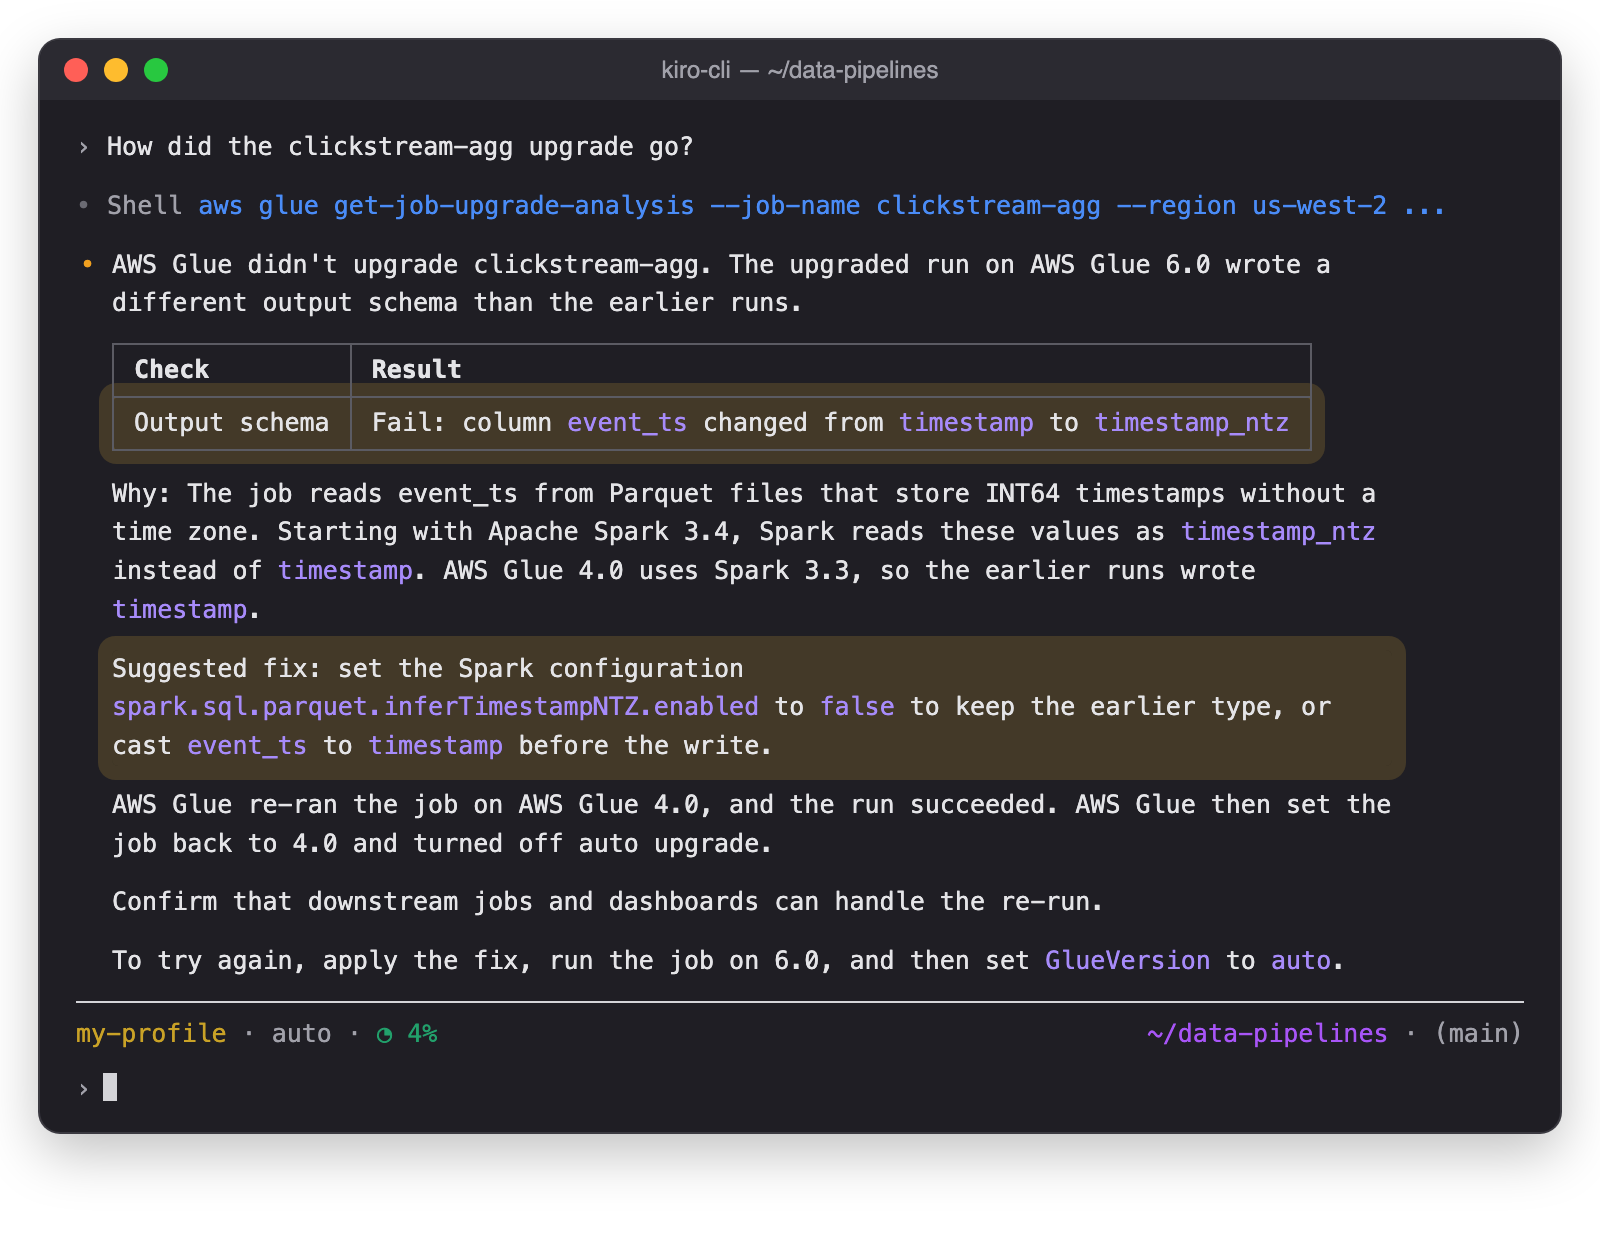
Figure 13: The agent explains why clickstream-agg didn’t upgrade
Your pipeline continues to run on AWS Glue 4.0. The auto upgrade evaluation summary shows what changed, so you can fix the job before you try again.
Conclusion
In this post, we showed how automatic version upgrades for AWS Glue jobs keep your Apache Spark jobs on the latest stable AWS Glue version. You used an AI agent to assess your jobs and turn on auto upgrade with email notifications. You then reviewed the eligibility summary, approved the upgrades, and checked the results in the auto upgrade evaluation summary.
With auto upgrade, your team no longer needs to plan and run an upgrade project for each job. AWS Glue analyzes each job and checks the upgraded runs against the job’s earlier runs. Your team reviews and approves each upgrade. This way you keep your whole fleet of AWS Glue jobs current instead of upgrading one job at a time.
Some jobs need code changes before they can move to a new version. For those jobs, use generative AI upgrades for Apache Spark in AWS Glue, which proposes and validates the code changes for the new version. After you update the code, set the job’s GlueVersion to auto so that AWS Glue keeps the job current from then on.
Auto upgrade is available today in all commercial AWS Regions. For the list of Regions, see Considerations and limitations in the AWS Glue User Guide. To get started, ask an AI agent with the managing-glue-jobs skill to assess the AWS Glue jobs in your account. Try auto upgrade, and share your feedback in the comments.
Special thanks
A special thanks to everyone who contributed from Engineering and Science to the launch of automatic version upgrades: Ezgi Maden, Akshara Ganapathi, Tina Shao, Raghavendhar Thiruvoipadi Vidyasagar, Shoukat Ghouse, David Zhang, Suthan Phillips, Prasad Nadig, Syed Mahmood, Karthik Seshadri, Pradeep Kumar Nalluri, Adam Rohrscheib, Eric Zhang, Tayo Adedokun, Weston Dunn, Kartik Panjabi, Shubham Mehta, Bryan Liles, Steffen Rochel, Kinshuk Pahare, Paul Meighan, and Rick Sears
About the authors
Get more from your Kiro investment with credit pooling: A guide for admins
Post Syndicated from Kirankumar Chandrashekar original https://aws.amazon.com/blogs/devops/get-more-from-your-kiro-investment-with-credit-pooling-a-guide-for-admins/
You’ve turned on credit pooling, or you’re about to, and now the decisions are yours: how many seats to keep, how many additional credits to buy, and what limit each developer gets. Set limits too tight and developers get blocked in the middle of a task. Set them too loose and one runaway automation job can drain the pool and pause Kiro for everyone. The data to make these calls is already in your AWS account, in your Kiro user activity reports. This post shows you how to read it.
The launch post, Share Kiro credits across your team with credit pooling, published November 4, 2026, introduced credit pooling: a shared pool of Kiro credits that every user in the pool draws from. Credits one developer doesn’t need automatically become available to a teammate who does.
Credit pooling is for organizations. It works with Kiro profiles that use AWS IAM Identity Center, Okta, or Microsoft Entra ID. Individual Kiro subscriptions, such as a personal account with a social login, can’t share credits through a pool, and credit pooling isn’t available in AWS GovCloud (US).
This post is a hands-on guide for admins. It describes how the credit pool behaves day to day and how to size it and dial in your limit settings from your own usage data. It also covers the best practices that keep it running smoothly.
How credit pooling works
In credit pooling, a seat is one user’s access to the pool, and each seat adds 500 monthly credits. When someone leaves, removing them frees their seat for someone else. For details, see Manage seats.
The following diagram shows how each seat’s 500 monthly credit inclusion flows into one shared pool, together with any additional credits you buy, and how every user draws from that pool. It also compares pooling with per-user credits.
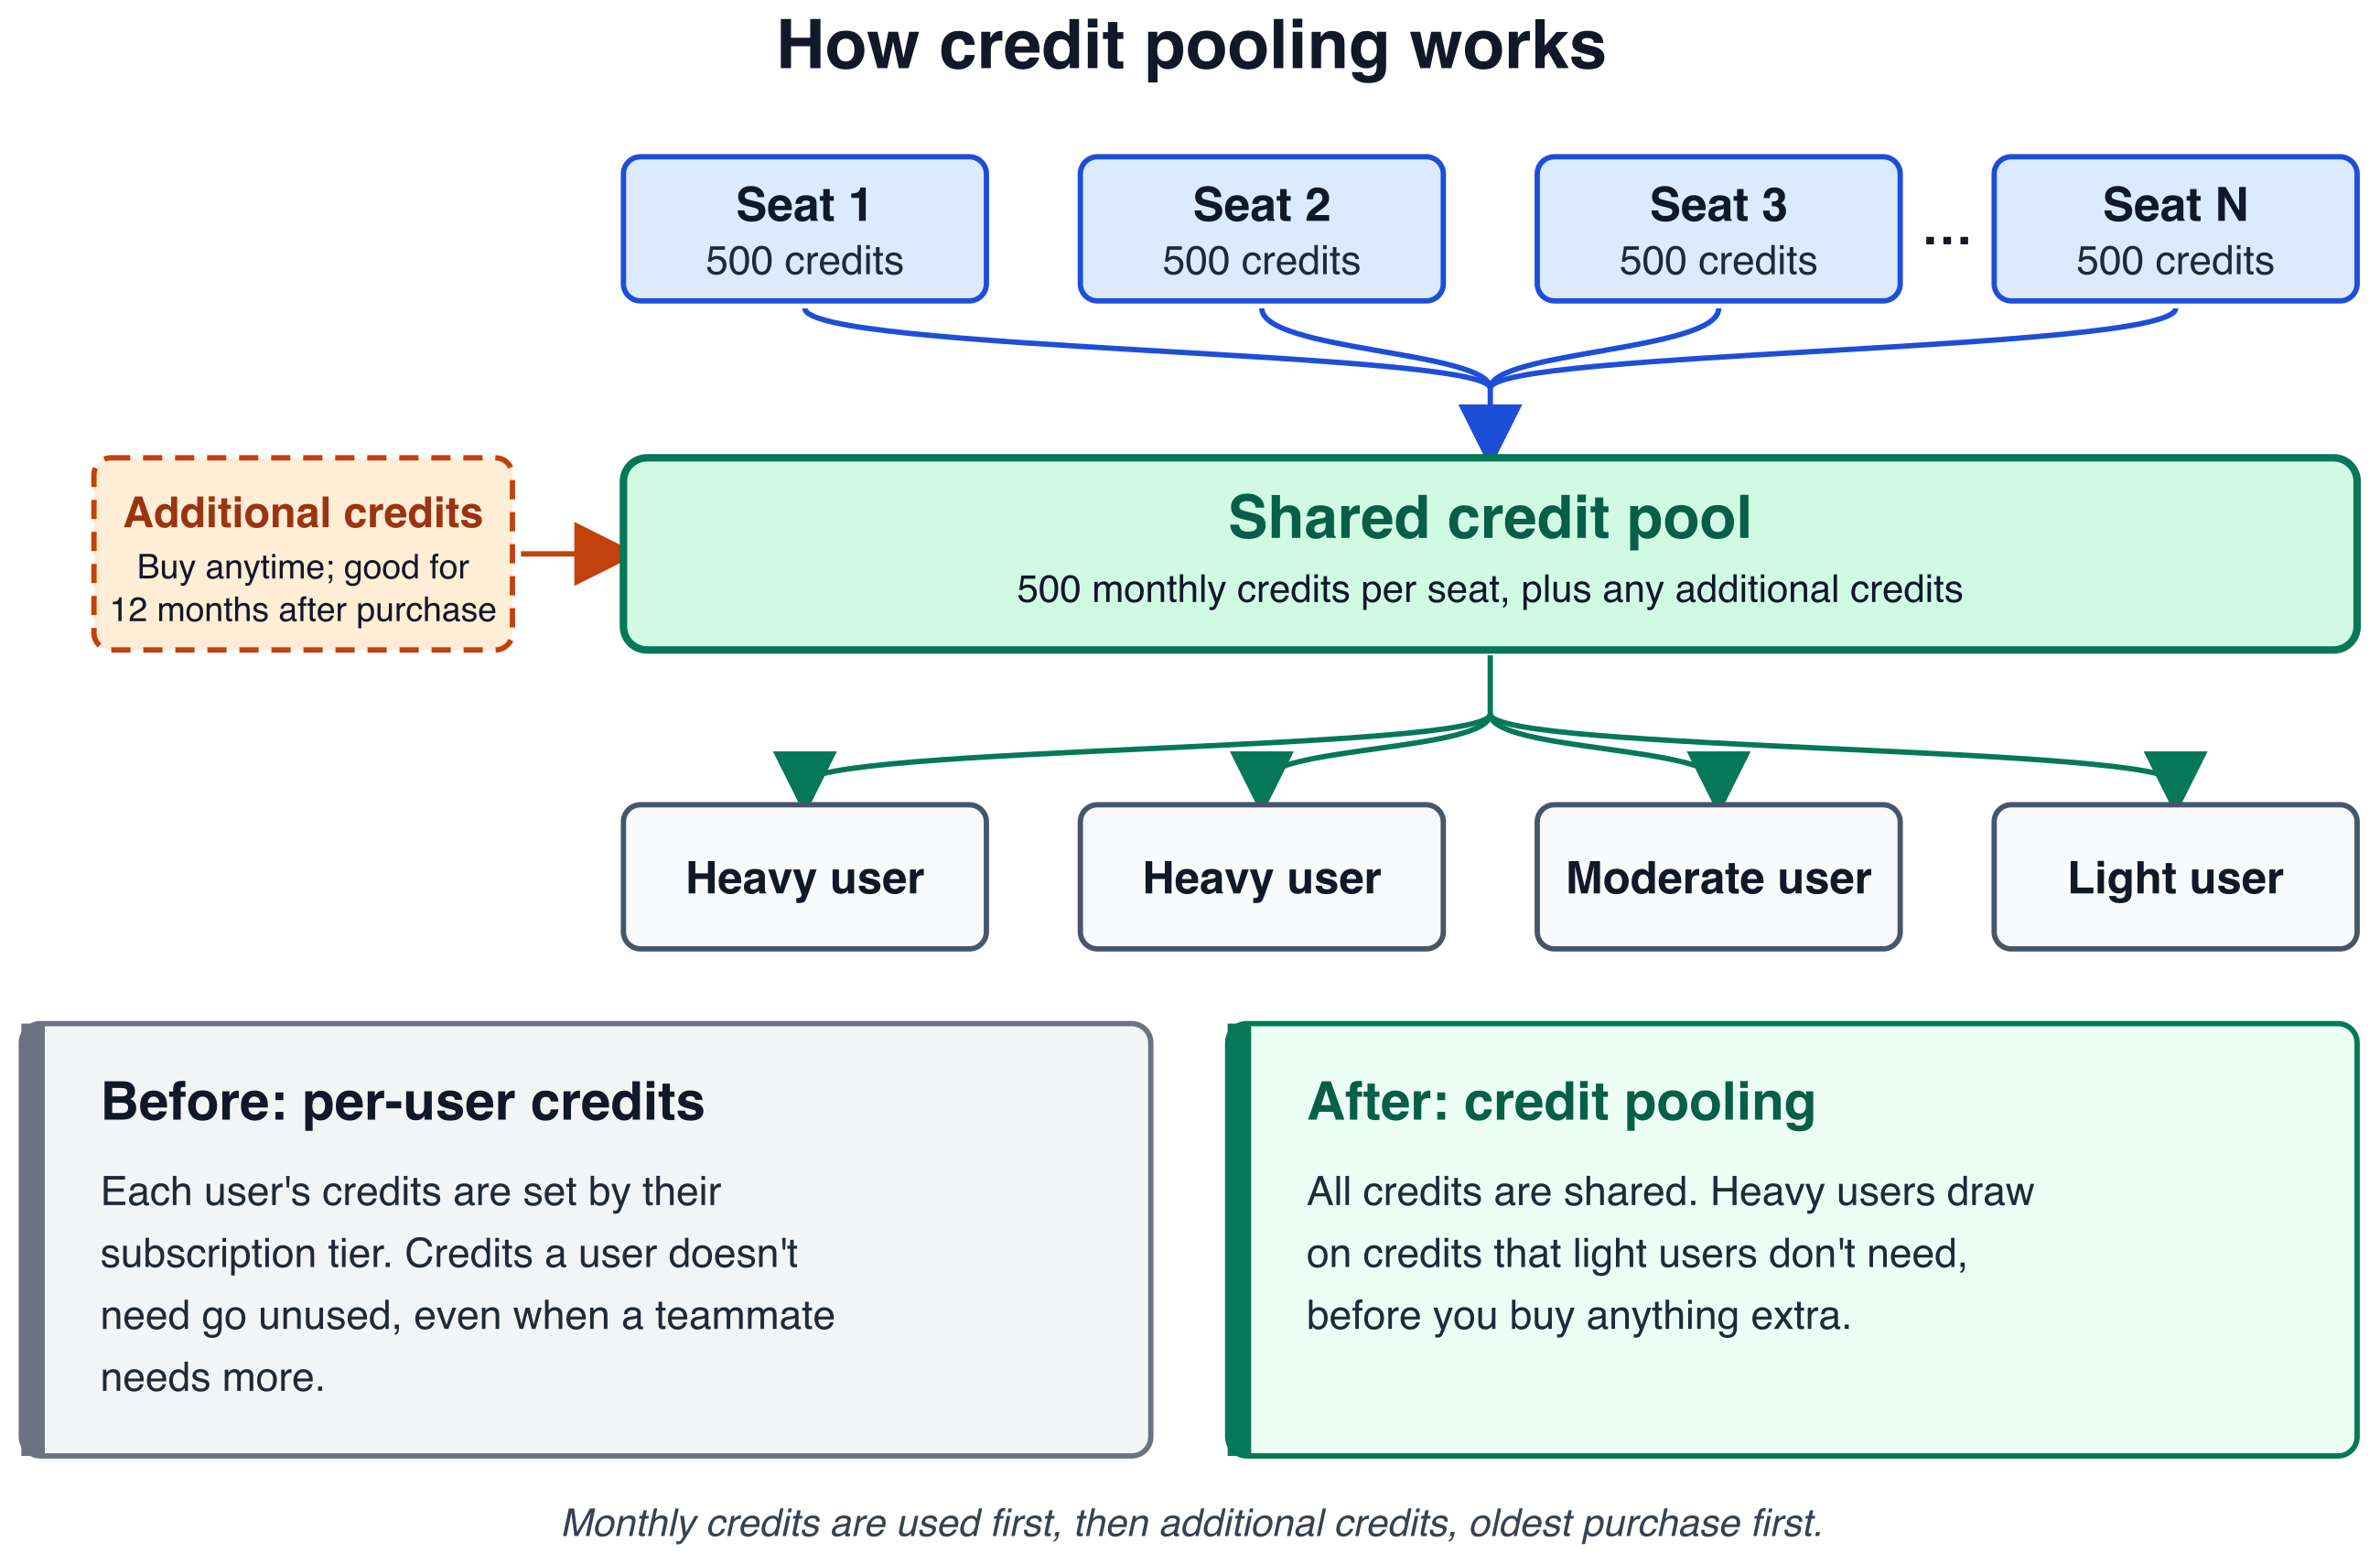
Figure 1: How each seat’s 500 monthly credits flow into one shared pool that every user draws from, compared with per-user credits
Here’s a short summary of the core mechanics and how they play out once your pool is running. Each billing cycle, every $20 seat adds 500 credits to the pool, so 100 seats add 50,000. Every seated user draws from the pool, including users that run Kiro in headless mode, such as continuous integration and continuous delivery (CI/CD) pipelines. These credits continue to reset at the end of each billing cycle, but now they’re available for anyone in the pool to use.
When the pool runs out
Admins can buy additional credits at any time in the Kiro console. Additional credits roll over and are good for 12 months after purchase.
Which credits are used first
Monthly credits are used first because they reset at the end of each billing cycle. After the monthly credits run out, Kiro draws from additional credits, starting with the oldest purchase.
Where the savings come from
Credit pooling can help you save in three ways:
- Shared credits absorb uneven usage. Your heaviest users draw on credits teammates don’t need before you buy anything extra.
- Seats follow your team. Add seats as people join, and remove a user to release their seat when they leave.
- Additional credits only when you need them. Buy them at any time, and they roll over for 12 months.
Walkthrough
Today, all you have is a daily report of each user’s consumption. This walkthrough turns that report into a plan in four steps. Step 1 loads the reports into Amazon Athena. Step 2 shows how each month used the pool. Step 3 recommends a seat count and a buffer of additional credits. Step 4 suggests a limit for each user.
Prerequisites
Before you start, confirm that the following are in place.
- User activity reports turned on for your Kiro profile. The analysis in this post is based on the daily user activity CSV reports that Kiro writes to an Amazon Simple Storage Service (Amazon S3) bucket. To set them up, including the bucket policy Kiro needs to write to the bucket, see Turn on the CSV report.
- Access to Amazon Athena, with permission to read the report location and write query results. For example, attach the AWS managed policy AmazonAthenaFullAccess, and allow
s3:GetObjectands3:ListBucketon your report bucket. - The number of seats you bought for a prepaid pool, or the number of users in a postpaid pool. You manage seats under Access management > Credit sharing in the Kiro console. The activity report can’t give you this number.
- An administrator role with the credit pooling permissions, so you can change seats, limits, and additional credits after the analysis.
Right-size your pool from your usage data
Your per-user activity reports record each user’s consumption.
Where to start depends on whether you already have data. If your team already uses Kiro, the activity report has recorded every user’s consumption all along, and the following queries run on that history as-is. Run Steps 2 and 3 now, before you pick a seat count. Step 3 tells you what that count needs to be.
If you are new to Kiro, there is nothing to analyze. Buy one seat for each person who needs access. That is the license, and the pool follows from it at 500 credits per seat. Keep a small buffer of additional credits (best practice 4), and start with generous limits (best practice 2). Either way, run one full billing cycle on pooling and come back to Step 2.
Step 1: Create the table and view
In the LOCATION line, replace the four capitalized placeholders. Use the Amazon S3 location you chose when you turned on the CSV report.
YOUR-BUCKET: the bucket name from your Amazon S3 location, for exampleamzn-s3-demo-bucket.YOUR-PREFIX: the folder after the bucket name, for exampleuser-activity-reports.ACCOUNT-ID: the 12-digit AWS account where your users are subscribed.REGION: the Region where you installed your Kiro profile, for example the US East (N. Virginia) Region (us-east-1).
For example, if your S3 location is s3://amzn-s3-demo-bucket/user-activity-reports/, the LOCATION line becomes s3://amzn-s3-demo-bucket/user-activity-reports/AWSLogs/111122223333/KiroLogs/user_report/us-east-1/. Keep the AWSLogs/.../KiroLogs/user_report/ part exactly as written. Kiro creates those folders itself.
Then create the view that the queries in the next steps read from:
Three details in that setup are worth knowing:
- OpenCSVSerde, not ROW FORMAT DELIMITED. Kiro quotes some fields, and the simpler row format leaves the quote marks on, which breaks any join on user id.
- The view finds columns by name, not position. Kiro has added columns to the report over time, so a position can hold a different column in an older file. The view reads each file’s header row and picks values by name. A column a file doesn’t have, like
usage_limitin older reports, comes back empty. - The table reads the first 20 columns, all as text. They must be text, because the first row of each file holds column names. Everything the queries use is within the first 14 columns, and anything past 20 is ignored. If a column the queries need ever moves past 20, add c21 and up to both the table and the view.
Confirm it worked before going further:
For an example 100-seat team with six months of reports, that returns:
If that returns zero users, the LOCATION prefix is wrong. If user_id values come back wrapped in quote marks, the table was created with ROW FORMAT DELIMITED.
Step 2: Re-run every cycle and let the data correct your estimate
This is the query you come back to each cycle. It returns one row per closed month at today’s seat count, so one run shows your whole history. Change only the seat count. It answers the right-sizing question directly: at the seats I pay for now, which months overflow the pool, and how much sat unused?
Sample output for the same team, one column per closed month. The current month is left out because it isn’t a full cycle:
For this team, credits that light users didn’t need covered 7,654 to 13,816 credits of heavier users’ demand every month, so it never bought additional credits. That’s how pooling can work. Even so, 2,000 to 11,700 credits went unused each month and 11 to 21 seats sat idle, which Step 3 turns into a plan.
Read it across, not down. If pool_credits_unused stays large for a couple of cycles, the seats behind it are not a one-off. Reclaim them from people who no longer need access and re-run next month to confirm.
If additional_credits_needed is climbing, buy additional credits earlier in the cycle rather than adding seats (see best practice 7). credits_covered_by_sharing, multiplied by $0.04, estimates what sharing saved you each month. When p90_credits_per_user and max_credits_per_user settle into a stable range, that is your signal to set limits with headroom above them.
seats_never_used counts seats with no activity that month, and cost_if_never_used_seats_reclaimed is your cost if you reclaimed them all. Treat it as a bound, not a target. Step 3 looks across several months before it recommends cuts.
The percentiles are your starting point for limits. p90_credits_per_user reflects your heavy users, and max_credits_per_user is the person who reaches a limit first. With fewer than a few dozen active users, lean on max. Step 4 suggests a limit for each person.
Step 3: Turn the numbers into a resizing plan
Step 2 shows what happened. This query turns that into a plan: seats to keep and reclaim, additional credits to hold, and what the change saves. In the EDIT ME block, set your seat count and how many closed months to look back over. Three months is a sensible default, because one quiet month doesn’t mean a seat is unneeded.
Sample output for the same team at 100 seats, looking back over July through September:
recommended_seats is one seat for everyone who used Kiro in the lookback or so far this month, however lightly, and seats_to_reclaim is the rest. The report can’t tell you who joined last week or is on leave, so check the names in the Kiro console before you reclaim anything.
additional_credits_to_keep is how far your busiest month ran past the recommended pool. Keep at least that many additional credits on hand going into each cycle (best practice 4). That’s a balance to hold, not an amount to buy every month, so check what’s already in your pool on the Kiro dashboard and buy only the difference. If Step 2 shows consumption climbing, keep more than this.
The cost columns compare the lookback months at your current seats with their cost at the recommended seats, averaged per month. Each month costs $20 per seat plus $0.04 per credit used beyond the pool, counted in the month it’s used. For this example team, reclaiming 14 idle seats would save about $213.30 a month on average, roughly $2,600 a year if the pattern holds. In July, the busiest month, about $200 of the $280 in seat savings came back as additional credits, which is why the buffer matters.
Step 4: Find users whose limits need to change
Seats and the pool are half of right-sizing. Per-user limits are the other half. This query lists the people whose limit is out of step with what they use. It flags anyone whose busiest month in the lookback reached 80% of their limit, anyone who stayed under 25% of their limit every month, and anyone with no limit set. For each one it suggests a new limit: their busiest month plus 25%, rounded up to the nearest 100 and never below the 500 credits a seat adds to the pool. It only lowers limits for people active in every month of the lookback, so a new joiner isn’t cut after one quiet month. Adjust the thresholds in the EDIT ME block.
Sample output for the same team, looking back over July through October so far:
The raise rows are the people closest to being blocked. In their busiest month, user021 used 994 of their 1,000 credits, so one heavy week might stop them. Raising it to 1,300 gives them room. A higher limit adds no cost until the credits are used.
The lower rows are people who use a small share of their limit, like user006, whose busiest month was 513 credits against a 3,000-credit limit. Lowering a limit doesn’t save money, because a credit costs the same whoever uses it. It limits the impact of a runaway automation job, so one person is less likely to drain the pool and block everyone. new_limit is never below what the user has already used this month, so lowering it doesn’t block them right away.
The limit when pooled rows are people still on a Pro, Pro+, Pro Max, or Power subscription. Their usage_limit is the tier’s monthly allowance, so above 100% means they need more than their tier includes, like user091. new_limit is the individual limit to allocate when you add them to the pool. Their usage is already counted in Step 3’s additional_credits_to_keep, so the buffer covers them too.
If several people in one group need the same change, change the group’s limit.
For the exceptions, set new_limit as an individual limit in the Kiro console. It takes priority over group and profile limits (best practice 2). Re-run this query each cycle to catch limits that need to move again.
Best practices for making credit pooling effective
These practices build on the numbers from the walkthrough and help you keep the pool sized without blocking anyone.
1. Learn your usage pattern first
Collect several months of data before you fine-tune anything. A couple of billing cycles show you who your heavy and light users are, how usage rises and falls through a sprint, and how quickly the pool draws down. Once you can see the trend, use the preceding analysis to size the pool and set limits.
2. Use the limit hierarchy strategically
With credit pooling, you can set per-user limits at three levels:
| Level | Priority | Use it for |
| Individual | Highest | Setting a per-user limit that applies to a specific user (for example, a user that runs automations, or someone testing heavily) |
| Group | Medium | Setting a per-user limit that applies to all members of a group |
| Profile | Lowest | Setting a default limit applicable to all users |
All limits are per-user. There are no aggregate caps at the group or profile level. A group limit sets the per-user cap for everyone in that group.
Where to start: If your team already uses Kiro, start from the limits Step 4 suggests. If you are new to Kiro, start with generous group and profile limits and tighten them after your first billing cycle, only where the data shows you need to. Over-constraining on day one creates friction and support tickets.
3. Group users by usage pattern
Consider grouping users by how they consume credits rather than only by org chart. For example, put heavy users (senior developers, machine learning engineers) in a group with a higher per-user limit, and light users (managers, reviewers) in a group with a lower one.
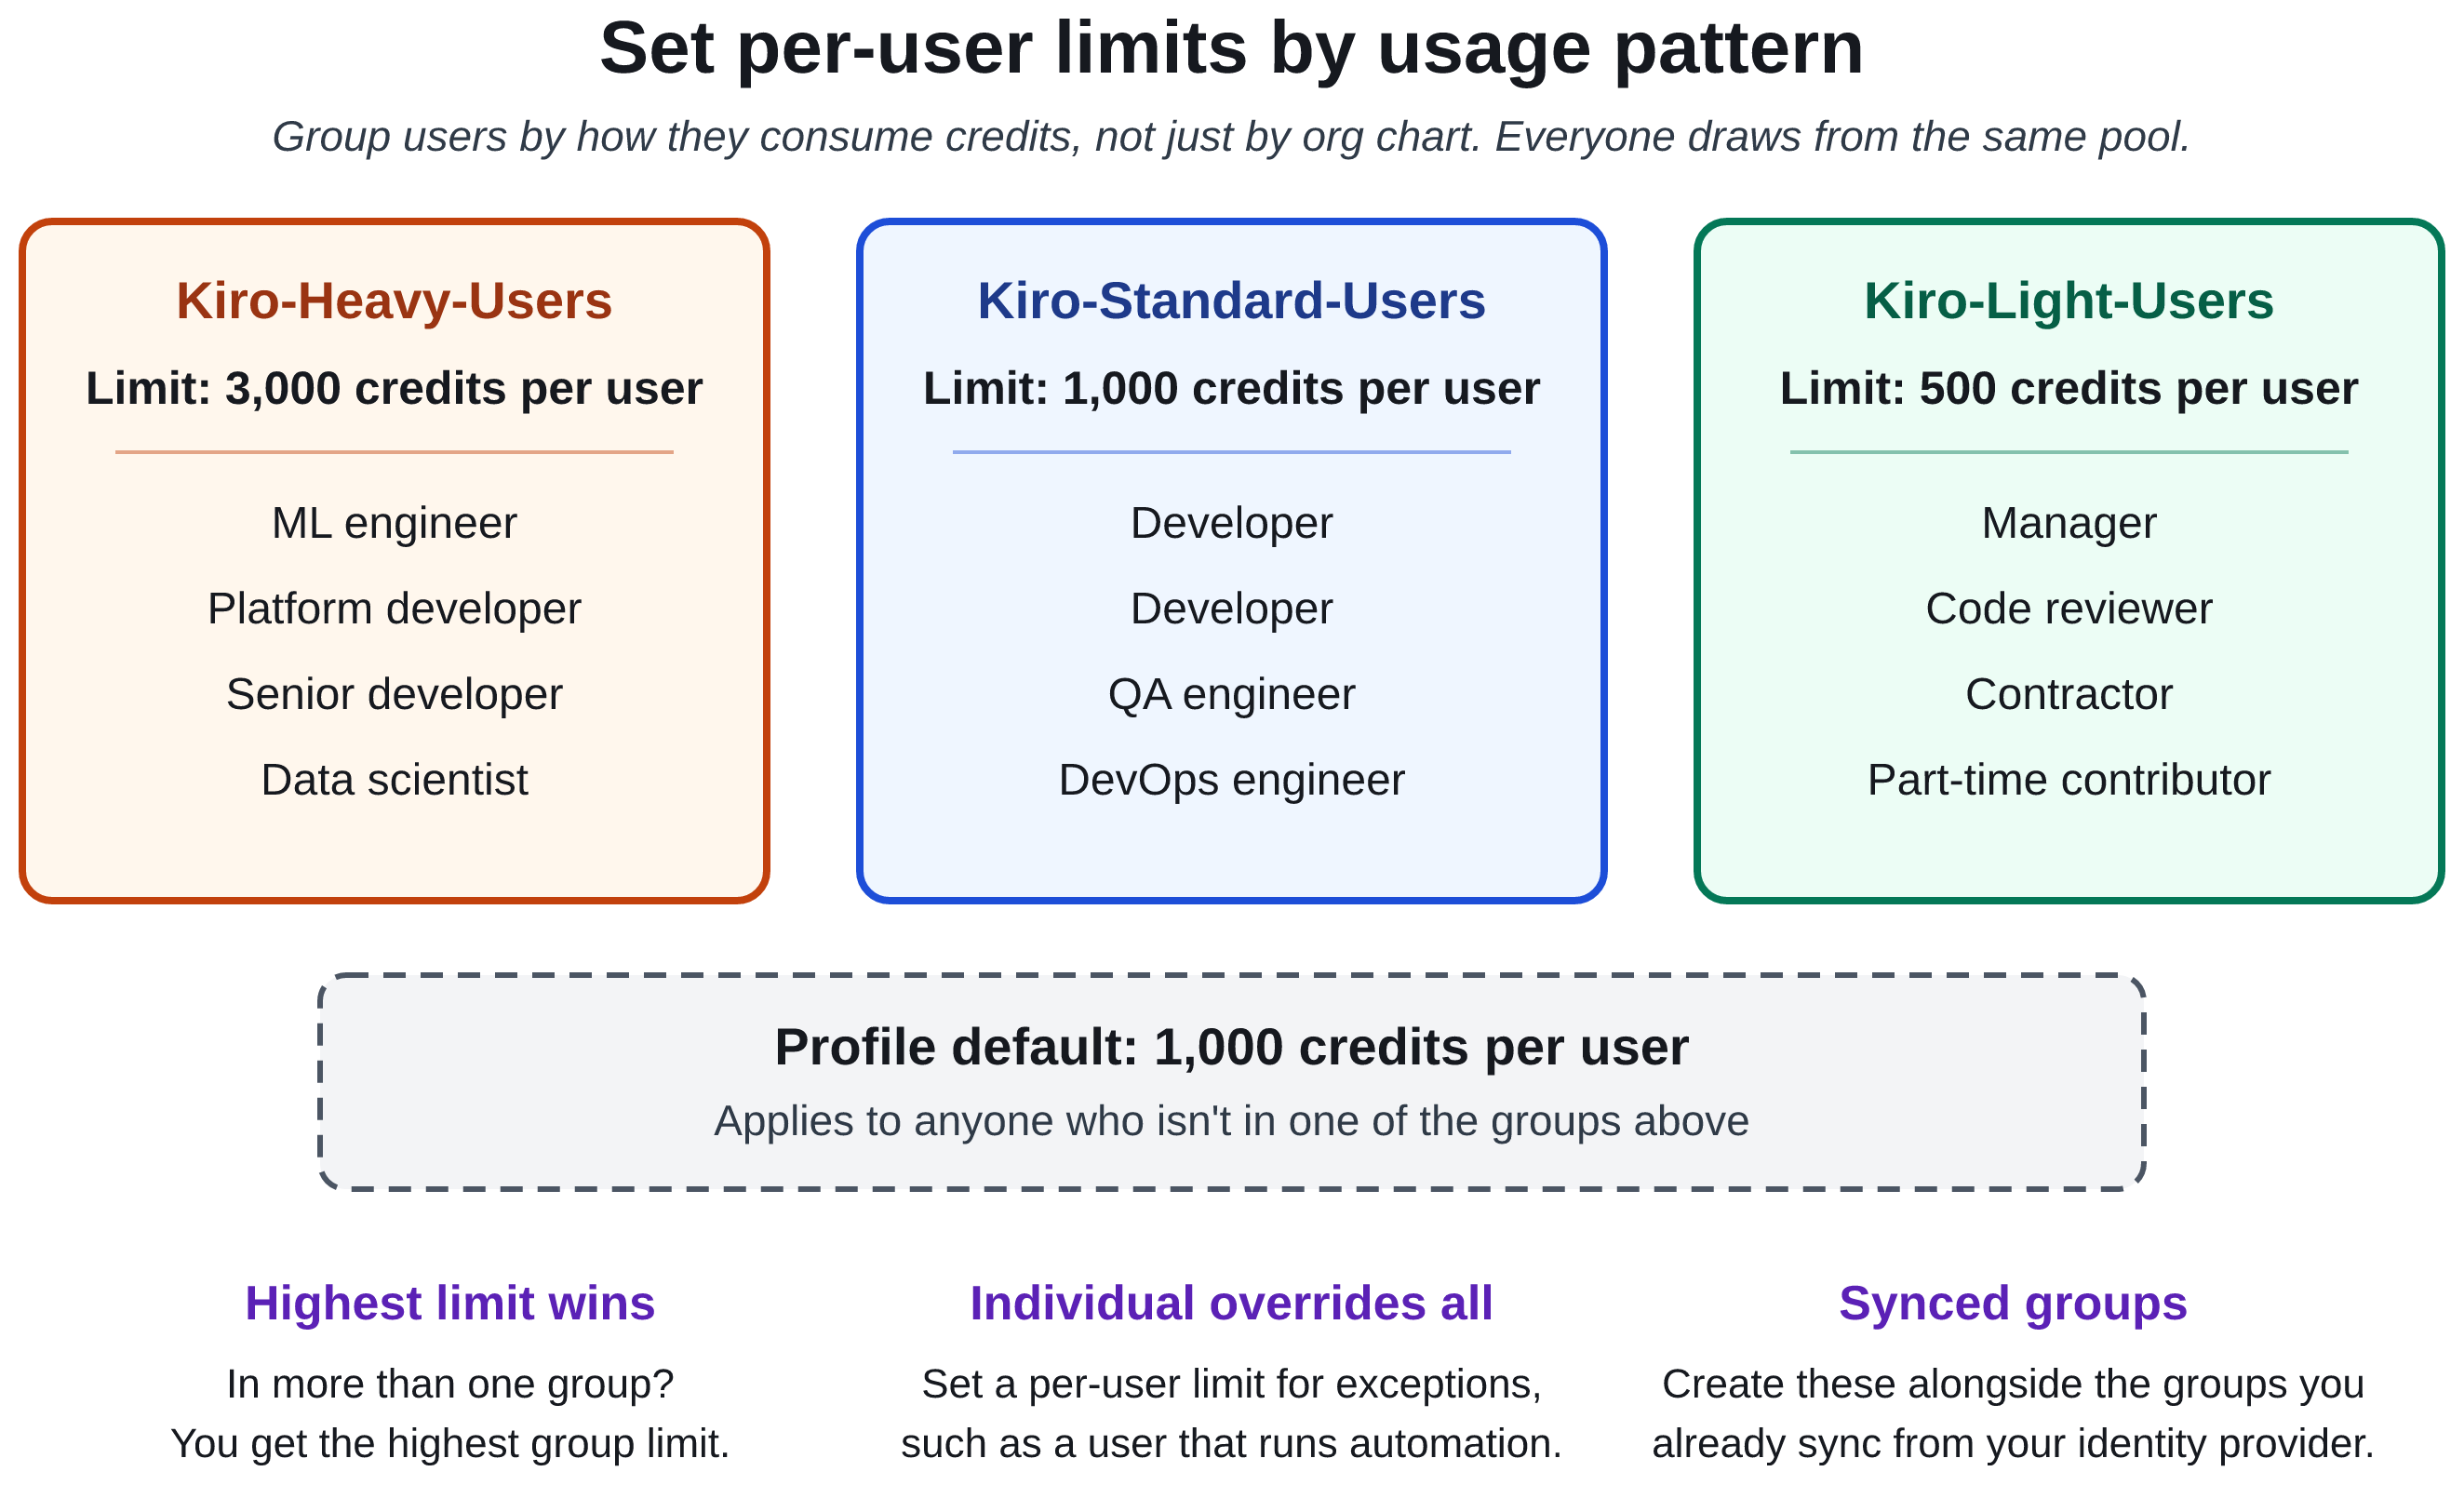
Figure 2: Grouping users by usage pattern to apply different per-user limits
If you sync groups from your identity provider: Your existing synced groups likely mirror your org chart. Create groups for credit pooling. For example, keep your synced “Engineering” group for access management, but create separate “Kiro-Heavy-Users” and “Kiro-Standard-Users” groups to apply different per-user limits. Users can belong to multiple groups, and the highest limit wins.
4. Keep a buffer of additional credits
When the pool is empty, everyone stops. Watch your pool threshold alerts and buy additional credits before the pool runs low. Because additional credits roll over for 12 months, buying early doesn’t waste them. Step 3’s additional_credits_to_keep shows how many to hold, based on your busiest month.
5. Review and adjust monthly
The Kiro dashboard gives you three views for this:
- Daily projected consumption with run-out date predictions.
- Credit usage breakdown (monthly compared to additional credits).
- Users sharing credits, credits left, and additional credits at a glance.
If you exhaust the monthly pool early, buy additional credits earlier in the cycle. If credits go unused, check whether some seats are inactive (best practice 7).
6. Use notifications to stay ahead
Credit pooling includes built-in alerts that notify admins at 80% and 100% by default:
- Pool threshold alerts: Get notified when the pool drops below configured levels.
- User usage alerts: Know when individual users approach their limits.
- Seat utilization alerts: Know when assigned seats near the number you bought.
Send these to the people who can act on them.
7. Right-size seats, and use credits rather than seats for headroom
A seat is an access license first and a credit contribution second. Treat them as two separate questions.
Seats with zero usage are the first place to look. You pay $20/month for a seat whether anyone signs in or not, and the seats_to_reclaim figure from Step 3 shows how many have gone unused for the whole lookback. Reclaim those from people who no longer need access.
Lightly used seats are a different matter. Don’t cut a license from someone who uses Kiro occasionally because their consumption is low. Their unused credits already go to the pool.
For headroom, buy credits rather than seats. If demand runs ahead of your pool, buy additional credits. Monthly credits reset at the end of the cycle. Additional credits last 12 months.
Things to keep in mind
- When the pool runs out, usage stops for everyone in it. Kiro blocks further usage, whatever each user’s limit, until you add credits.
- Mid-cycle limit changes take effect immediately. If you lower a user’s limit below their current consumption, they’re blocked right away. If you increase their limit, they can immediately resume their AI use. Plan limit changes at the start of a billing cycle when possible.
- In a prepaid pool, seats are billed whether occupied or not. Every seat contributes credits and costs $20/month. Factor in your idle seats when calculating return on investment.
Getting started
If you have a Kiro profile with users signing in through single sign-on (SSO), you’re ready to go:
- In the Kiro console, go to Access management.
- On the Subscriptions tab, choose Switch to credit sharing.
- Follow the wizard to select users or groups.
Switching is irreversible: a user you move can’t go back to an individual subscription. Have each user’s Step 4 limit ready to apply once they’re in the pool.
Key details at a glance
The following table summarizes the numbers and rules covered in this post.
| Item | Detail |
| Credits per seat | 500/month (shared) |
| Cost per seat | $20/month |
| Additional credits | $0.04 per credit, good for 12 months |
| Monthly credit reset | End of billing cycle |
| Consumption order | Monthly → Additional (oldest purchase first) |
| Limit hierarchy | Individual > Group > Profile |
Start sharing
Credit pooling turns unused individual capacity into a shared resource. Teams with uneven usage can get more from the same spend, and limits at every level help you stay in control.
Ready to try it? Head to the Kiro console and turn on credit sharing under Access management. For details on seats, limits, and monitoring, see Credit pooling in the Kiro documentation.
About the authors
Step-up authentication: how to right-size authentication to risk
Post Syndicated from Abrom Douglas original https://aws.amazon.com/blogs/security/step-up-authentication-how-to-right-size-authentication-to-risk/
Not every action a user takes in an application carries the same risk. Viewing an account balance in a banking application isn’t the same as wiring several thousand dollars to a new payee. In practice, though, many applications ask users to prove their identity once at sign-in and then treat every action the same from that point on, whether that sign-in used a password alone or included multi-factor authentication (MFA). That creates a tension: if the sign-in is strict enough for the most sensitive operation, everyday tasks carry unnecessary friction. If it’s easy enough for everyday tasks, the most sensitive operations might not be protected well enough. Even a strong sign-in from hours earlier says little about who is at the keyboard when a high-risk request arrives.
Amazon Cognito now resolves that trade-off by supporting step-up authentication, which records the authentication assurance level and the methods used, and including both in the JSON web tokens (JWTs) it issues. You ask for a target assurance level when a user signs in. Amazon Cognito returns the level the user reached in an acr claim (authentication context class reference) and the methods they completed in an amr claim (authentication methods reference). These claims are part of the OpenID Connect Core specification, so your application can reason about authentication strength in a standard way and match it to the potential risk of what the user is trying to do. In this post, I explain how the claims support step-up authentication and walk through four patterns that put them to use: transaction-level step-up in a banking app, varying risk postures across a portfolio of applications, step-up enforced on API and SDK sign-in, and authentication assurance carried across a federated third-party OpenID Connect (OIDC) identity provider.
You can request authentication levels through Amazon Cognito managed login using the standard OIDC acr_values and max_age parameters, and through the SDK and API using the USER_AUTH flow with TARGET_ACR_VALUES and MAX_AGE. Requesting step-up authentication requires the Essentials or Plus feature plan. ; For the complete list of features, behaviors, and limitations, see the Authentication levels with ACR and AMR claims.
What ACR and AMR tell your application
Amazon Cognito defines four assurance levels, and the factor combinations that satisfy each one are fixed. You can use the default names as is or rename the level URIs to fit your organization’s own naming scheme. Renaming changes only the label. If you need to relate Amazon Cognito levels to a framework such as NIST SP 800-63 or eIDAS, make that mapping in your application. The following are the default Amazon Cognito defined levels.
- Level 1 (
urn:cognito:loa:1) is password only. - Level 2 (
urn:cognito:loa:2) is a single one-time password (OTP) over SMS or email. - Level 3 (
urn:cognito:loa:3) is a passkey on its own, or a password combined with an SMS or email OTP. - Level 4 (
urn:cognito:loa:4) is the highest: a password with a time-based one-time password (TOTP) code from an authenticator app.
Amazon Cognito assigns the highest level the user’s completed factors fully satisfy, so a user who signs in with a password and a TOTP code lands at level 4, even though they also met the assurance requirements for every level below it.
Four claims in the token facilitate a step-up decision. The acr claim is the level the sign-in reached and is what your application compares against what the operation requires. The amr claim lists the methods behind that level, so you can confirm a specific factor was used. The auth_time claim records when the user last authenticated interactively and is what max_age is measured against. The iat claim only records when the token was issued, so a refreshed token carries a new iat but keeps its old auth_time. Finally, send a nonce in the request and verify it on the returned ID token, so the result is tied to the request you made.
The following is an example access token for a user completing a level 4 authentication. Notice the four claims I’ve discussed: acr, amr, auth_time, and iat.
Two important behaviors are worth understanding before you build on this. First, a token refresh preserves the acr and amr values, so a user who reached level 4 keeps level 4 across refreshes and isn’t asked to prove it again on every rotation. Second, a refresh doesn’t reset the auth_time claim. That field records when the user interactively authenticated, not from a non-interactive token refresh. This is what lets you reason about freshness of authentication separately from assurance strength.
At a high level, every step-up interaction in this post follows the same loop: the application checks the token it already holds, redirects for a stronger level only when the operation requires more than the user has, and re-validates the acr claim on the freshly issued token before it proceeds. The following diagram provides a general step-up authentication flow.
Figure 1: General step-up authentication flow to access a sensitive operation
How you request a level, and what stays your responsibility
The request side is deliberately straightforward. On managed login you add acr_values and optionally max_age to the or endpoint. In the SDK and API, you pass TARGET_ACR_VALUES and MAX_AGE in the USER_AUTH flow of the API. Both acr_values and TARGET_ACR_VALUES accept an ordered list of target levels. The same parameters work whether you’re setting the level for an initial sign-in or raising the level of a user who is already signed in; the patterns later in this post show both. Amazon Cognito acts only on what you send. It doesn’t infer the level you meant, so if you omit the parameter or request the wrong level, the user might not be stepped up the way you intended.
That points to the part your application and API owns: what assurance authentication level is needed. Amazon Cognito issues a token that honestly reports the level the user reached based on what your application requested. For example, deciding that a given operation requires an assurance level 3, checking the token’s acr against that requirement, and refusing the operation when it falls short is enforcement your application and API performs. Amazon Cognito produces the evidence; your code acts on it. In practice, that means checking the token you already hold before you redirect, so you don’t send a user to re-authenticate who already meets the bar, and validating the acr and auth_time claims on the tokens Amazon Cognito returns before you grant access. Amazon Cognito computes these claims itself, so you can’t customize, add to, or suppress them with a pre-token-generation Lambda trigger.
There is one more detail that saves debugging time later. If you rename your acr level URIs after tokens have already been issued, an older token might carry an acr value that no longer matches any configured level. Amazon Cognito treats that as an unrecognized level rather than an error. It still honors the token’s amr values and prompts only for factors not already present, without crediting any particular level. The amr list, in other words, remains meaningful even when a renamed level string goes stale. See Configuring ACR level names to learn how to configure this.
With the claims and the division of responsibility in place, the following four patterns show how they work in practice. Each one applies the same loop from Figure 1 to a different situation: a single application, a portfolio of applications, API-driven sign-in, and federation.
Pattern 1: Transaction-level step-up in a banking app
Consider a retail banking application. Signing in and viewing balances is routine, and the bank is comfortable requiring a moderate assurance level for it. Moving money is considered a privileged action, and a large transfer deserves stronger proof that the person at the keyboard is really the account holder.
The bank sets its baseline at level 2, so a user signs in with a one-time code over SMS or email and can see balances, statements, and pending transactions. When that same user initiates a transfer above $1,000, the application’s own policy says the operation requires level 4. Before it shows the transfer initiation screen, the application inspects the acr claim in the token it already holds. The user authenticated at level 2, level 2 is below the required level 4, so the application redirects the user to managed login with acr_values=urn:cognito:loa:4.
Amazon Cognito now requires the user to complete a factor combination that satisfies level 4, for example entering their password and then a TOTP code from their authenticator app. When authentication finishes, Amazon Cognito issues fresh tokens with acr set to urn:cognito:loa:4, amr set to ["pwd", "otp", "mfa"], and a fresh updated auth_time claim. The application validates that the new token meets its requirement and only then lets the transfer proceed. A transfer under the threshold never triggers any of this, so the everyday experience stays light and the friction lands exactly where the risk is.
The application logic reads naturally, here’s a pseudo JavaScript snippet:
You can extend the same idea to freshness. A bank might accept a level 4 session for a high-value transfer only if the user authenticated within the last 5 minutes, which you express by adding max_age=300 to the request. Amazon Cognito compares that window against the auth_time claim in the access token and reauthenticates the user if the window has passed, even if the token was refreshed seconds ago.
Pattern 2: A portfolio of applications with different risk postures
Assurance levels are just as useful across a set of applications as they are within one. Suppose an organization runs five applications from a single Amazon Cognito user pool using managed login, and each one carries a different risk posture.
An internal cafeteria menu is low risk, so it’s fine with level 1, password only. An employee directory and an expense viewer hold personal data but nothing that moves money, so they require level 2: a one-time code over SMS or email on top of the password. A source code portal warrants a passkey or a password plus a one-time code, which is level 3. The production financial console is the crown jewel, so it demands level 4: a password with a TOTP code.
Each application requests its own floor by setting acr_values to the level that matches its risk, and each validates the acr claim on the returned token before granting access. Because the applications share a user pool, managed login keeps a single sign-on (SSO) session across them. A user who has already reached level 4 for the financial console is redirected to managed login when they open another application, finds the existing session, and receives tokens for that application without another prompt, provided the application doesn’t send a max_age that the session has outlived. Each application then compares levels by rank, so a level 4 token satisfies a level 2 floor. Someone who signed in at level 1 for the cafeteria menu, on the other hand, is stepped up the first time they open the expense viewer, because level 1 doesn’t meet the level 2 floor that the application enforces. The user pool stays single and central; the assurance requirement travels with each application’s own policy.
Renaming the level URIs helps here. If the organization already classifies systems against an internal assurance standard, it can set AcrConfiguration on the user pool so that, say, level 3 reports as urn:example-corp:assurance:standard and level 4 as urn:example-corp:assurance:high. The factor combinations behind each level stay fixed; only the names change, so every application validates against strings its developers already recognize.
Pattern 3: Step-up on API and SDK sign-in
Managed login covers browser-based flows, including federation, but plenty of clients authenticate directly against the Amazon Cognito API, and the same assurance model applies there, such as using the USER_AUTH flow with the InitiateAuth API. This matters for a mobile app, a desktop client, or a service that drives sign-in programmatically and needs to raise assurance before a sensitive call.
Take a mobile trading app that signs its users in with the SDK. A user opens the app with a password and reaches level 1, which is enough to browse watchlists and market data. When they place a trade, the app’s policy requires level 4. Because the app authenticates through the API rather than a browser redirect, it starts a new USER_AUTH flow and passes the access token it already holds along with TARGET_ACR_VALUES, requesting the level it needs. Amazon Cognito drives the user through a factor combination that satisfies level 4, then returns tokens whose acr claim the app validates before it submits the order. The InitiateAuth request would look similar to the following API call.
Passing the access token the app already holds lets Amazon Cognito step the user up from the factors in that token; without it, Amazon Cognito authenticates the user from scratch. The MAX_AGE parameter behaves the same way it does on managed login. It ties the requirement to auth_time, so a trade placed after the window elapses forces a fresh authentication even if the app refreshed its tokens in the meantime. One behavior specific to the API path is worth knowing when you test on a lower Cognito feature plan. If you request step-up through InitiateAuth on a user pool that isn’t on the Essentials or Plus plan, the API returns a FeatureUnavailableInTierException. Managed login handles the same situation differently: the authorize endpoint silently ignores acr_values and proceeds with normal authentication rather than raising an error.
Pattern 4: Carrying assurance across a federated OIDC identity provider
The three patterns so far assume Amazon Cognito is where the user authenticates and the authoritative source for the identity. Many organizations federate sign-in to a third-party OIDC provider, so the person proving who they are is doing it against an external identity provider (IdP), while Amazon Cognito brokers the session. The assurance model follows them there.
When your application requests a level, it sends acr_values and optionally max_age to the Amazon Cognito authorize endpoint exactly as before. If that user is configured to federate through an OIDC IdP, Amazon Cognito sends the authorization request to that IdP on the user’s behalf. It translates the level you requested into the acr value the IdP expects, using the mapping you configured, and passes max_age along with it. A standards-compliant OIDC IdP honors acr_values the same way Amazon Cognito does: it drives the user through an authentication that satisfies the requested level, and it returns its own acr value describing what the user reached. max_age carries forward in the same way, so a freshness requirement is enforced at the provider that actually authenticates the user rather than being lost at the broker. Keep in mind that this is only supported with OIDC identity providers.
The request is unchanged from the application’s point of view. It still directs to Amazon Cognito:
The interaction gains a third participant, the downstream IdP, but the assurance requirement is persisted through the entire federated authentication flow as shown in figure 2.
Figure 2: Federation with an OIDC third-party IdP, persisting the acr_values and max_age request parameters
The value that comes back from a partner IdP won’t use Amazon Cognito’s level URIs, so this lets you map the provider’s acr values onto its own levels with the AcrMapping field on the OIDC IdP configuration. A partner IdP that reports, say, https://partner.example/assurance/strong can be mapped to Amazon Cognito level 3 (urn:cognito:loa:3), so that by the time the token reaches your application the acr claim speaks the same vocabulary regardless of whether the user authenticated locally or through a federated provider. Your resource server keeps a single enforcement rule and authorization logic and doesn’t need to have special handling depending on where the user ultimately authenticated. See Step-up authentication for federated users to learn how to map external OIDC IdP acr levels to Cognito.
This is the same pattern that RFC 9470, the OAuth 2.0 Step Up Authentication Challenge Protocol, describes: the assurance level is requested at the edge of your application, travels through Amazon Cognito to whatever provider authenticates the user, and returns normalized to a vocabulary your code already understands. A user federating from a corporate IdP and a user signing in against the same user pool directly both arrive at your resource server carrying an acr claim that means the same thing.
Conclusion
In this post, I showed you how the acr and amr claims in Amazon Cognito let you match authentication strength to the risk of what a user is doing, instead of settling for one bar at the front door. Your application requests a target level with acr_values and max_age (or TARGET_ACR_VALUES and MAX_AGE in the USER_AUTH flow), Amazon Cognito reports the level reached and the methods used, and your application enforces what each operation requires. The four patterns, from a banking transfer to a federated third-party IdP, follow that same loop, and one enforcement rule at your resource server covers every sign-in path.
The larger shift is that assurance is now something Amazon Cognito expresses in a standard way and your application reasons about directly, without building your own step-up tracking. To get started, move your user pool to the Essentials or Plus feature plan, decide the level each operation requires, and add acr_values to your existing authorize requests. For the complete parameter reference and federated behavior, see the Amazon Cognito Developer Guide.
If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.
A Conversation with House Democratic Leader Hakeem Jeffries
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=DpCrXJh3Ug4
Long-term Amazon Redshift observability with Datadog and Amazon S3 Tables
Post Syndicated from Raghu Kuppala original https://aws.amazon.com/blogs/big-data/long-term-amazon-redshift-observability-with-datadog-and-amazon-s3-tables/
Building long-term observability for Amazon Redshift starts with a question: what happened in your data warehouse last month, last quarter, or last year? Amazon Redshift captures operational history across more than 25 system views. These views range from query execution details in SYS_QUERY_HISTORY and full query text in SYS_QUERY_TEXT to connection activity, user changes, workload management events, and resource consumption metrics. Together, these views form a detailed record of the operations running inside your Amazon Redshift clusters and Amazon Redshift serverless workgroups. Amazon Redshift retains this data for 7 days. After that window closes, the history is gone. You lose the ability to audit past activity, investigate slow-moving regressions, or satisfy compliance requirements that can span months or years.
The system table integration with Amazon S3 Tables, a capability of Amazon Redshift, changes this. When you enable the integration, Amazon Redshift automatically and continuously delivers system table data as Apache Iceberg tables to Amazon S3 Tables in your account. You own the data, you set the retention policy, and S3 Tables handles compaction and snapshot maintenance. You can query the exported data with Amazon Redshift, Amazon Athena, or any Iceberg-compatible engine. There’s no charge for delivery. You pay only for S3 Tables storage, requests, maintenance, and the engine you use to read the data.
AWS and Datadog collaborated to make this exported data actionable for observability. Datadog, an AWS Specialization Partner and AWS Marketplace Seller, provides an observability and security platform for cloud applications. Datadog Data Observability helps data teams improve the reliability of data for analytics and AI. It combines quality monitoring for warehouses such as Amazon Redshift with jobs monitoring for pipelines that run on AWS Glue, Amazon EMR, Apache Airflow, and dbt. It then connects them with lineage that spans from source pipelines to downstream dashboards. By reading query history directly from S3 Tables, Datadog turns it into column-level lineage, query analysis, and context for quality alerts, without adding load to your warehouses to collect it. For AWS managed monitoring of Amazon Redshift metrics and logs, you can also use Amazon CloudWatch. Datadog Data Observability is billed separately by Datadog.
In this post, we show how to configure Datadog Data Observability to read Amazon Redshift query history from S3 Tables. We walk through granting Datadog read access and using the query history for column-level lineage, query analysis, and data quality monitoring.
Solution overview
Datadog Data Observability uses Amazon Redshift query history to build column-level lineage, analyze query performance, and give context to data quality alerts. Previously, Datadog collected this history by running read-only SQL against each warehouse every hour. With this solution, Datadog reads the same history from S3 Tables instead. The following diagrams show the solution at a high level and compare query history collection before and after the integration.
Figure 1: High-level solution overview
Figure 2: Query history collection before and after the S3 Tables integration
This approach offers the following benefits:
- Retention beyond 7 days. Query history remains in your account for as long as you choose to retain it. Because history is kept in S3 rather than expiring after 7 days in the cluster, Datadog can backfill any collection gap when it resumes. You don’t lose queries or lineage. Your audit and compliance teams also keep a long-term record of query activity in your own account.
- No added load on the warehouse. Datadog reads the Iceberg tables through the S3 Tables Iceberg REST endpoint. Collecting query history doesn’t run queries on your clusters or workgroups or consume their compute.
- One view across warehouses. Datadog combines query history from every connected cluster and workgroup into a single lineage graph, together with other connected tools such as dbt, Apache Airflow, Tableau, Looker, and Power BI.
The following diagram illustrates the solution architecture.
Figure 3: Solution architecture
The workflow consists of the following steps:
- Amazon Redshift periodically writes completed query records from
SYS_QUERY_HISTORYandSYS_QUERY_TEXTto the AWS managedaws-redshifttable bucket in Amazon S3 Tables. An isolated background process handles these writes, separate from your production workloads. - Datadog uses the AWS Identity and Access Management (IAM) role from your Datadog AWS integration to read new rows through the S3 Tables Iceberg REST endpoint. Because data is delivered in batches at a fixed frequency, Datadog tracks the last batch it read, so no batch is skipped or read twice.
- Datadog masks sensitive literals in the query text, parses each query into column-level lineage, and groups similar queries into normalized query profiles.
- Datadog still connects to Amazon Redshift for table metadata, such as schemas and row counts, and to run the data quality monitors that you configure.
Prerequisites
To implement this solution, you need the following:
- An AWS account with one or more Amazon Redshift provisioned clusters (RG or RA3 node types) or Amazon Redshift Serverless Workgroup.
- The system table integration with Amazon S3 Tables enabled for each warehouse you want to monitor. At minimum, enable
sys_query_historyandsys_query_text. Datadog reads per-warehouse exports, so set the granularity toclusterfor provisioned clusters orworkgroupfor Serverless namespaces. To enable the integration, see Enabling system table integration with Amazon S3 Tables. - The Amazon S3 Tables integration with the AWS Glue Data Catalog enabled in your account and Region. This is a one-time setup step. If you already integrated S3 Tables with the AWS Glue Data Catalog, no further action is needed. For instructions, see Integrating Amazon S3 Tables with AWS analytics services.
- An IAM principal with the following permissions:
redshift:EnableLogging(provisioned) orredshift-serverless:UpdateNamespace(Serverless).s3tables:CreateTableBucket,s3tables:PutTableBucketEncryption, ands3tables:PutTableBucketPolicy.
- The AWS Command Line Interface (AWS CLI) installed and configured.
- A Datadog account with the Datadog AWS integration configured and your warehouse connected to Datadog Data Observability for Amazon Redshift.
- Access to the Datadog Data Observability S3 Tables preview. To request access, contact your Datadog account team.
Note: Plan your encryption strategy before enabling the integration. If you encrypt the tables with a customer managed AWS Key Management Service (AWS KMS) key, you can’t change the key after the tables are created. If you plan to consolidate warehouses later, choose a shared AWS KMS key from the start.
Grant Datadog read access to the system tables
Datadog reads the system tables with the IAM role that your Datadog AWS integration uses. Complete the following steps:
- On the IAM console, in the navigation pane, choose Roles, then choose the role used by your Datadog AWS integration.
- Choose Add permissions, then choose Create inline policy.
- Choose the JSON tab and enter the following policy, replacing
<region>and<account-id>with your values:
- Enter a name for the policy, for example
DatadogRedshiftSystemTablesRead, and choose Create policy.
Note: If you encrypted the tables with a customer managed AWS KMS key, also grant the role kms:Decrypt permission on that key.
Use S3 Tables as the query history source in Datadog
During the preview, your Datadog account team enables S3 Tables as the query history source for your Datadog organization. Datadog then reads query history for each connected Amazon Redshift warehouse from S3 Tables instead of from the warehouse. Datadog tracks its position in the query history for each warehouse, so switching between sources doesn’t skip or duplicate queries.
Analyze query history in Datadog Data Observability
Query history feeds three parts of Datadog Data Observability:
- Lineage. Shows how data moves between tables, jobs, and dashboards.
- Query analysis. Shows who produces and consumes that data, and at what cost.
- Quality monitoring. Uses both to decide which tables to watch and to explain each alert.
Datadog builds all three from the same query history, so they work the same way whether the history comes from the warehouse or from S3 Tables.
The examples in this section use an Amazon Redshift table named analytics.fct_orders. A nightly job loads it from staging.stg_orders, and a Tableau dashboard reports revenue from it.
Note: The figures use a sample environment, so they show a database named prod and a table named int_orders_enriched instead of analytics.fct_orders.
Column-level lineage
Figure 4: End-to-end lineage upstream of, through, and downstream of the prod database
Datadog parses each query in the history into column-level lineage. To explore it, complete the following steps:
- Choose Data Observability, then Lineage.
- Search for
prodto anchor the graph on the database. Figure 4 shows the result: source tables such asordersflow through theraw,staging, andintermediateschemas intomarts. To focus on a single table such asusers, search for that table instead. - Review upstream tables and jobs to the left, and downstream tables and dashboards to the right. An Upstream issue label marks assets affected by a problem further upstream.
- To see column-level lineage, expand a table to show its columns and how each one flows into downstream tables. To trace a single column from source to dashboard, change the asset type to Column and search for it.
In addition to Amazon Redshift, the lineage graph supports other sources. When you connect other integrations, upstream jobs from Apache Airflow or dbt and downstream dashboards from Tableau, Looker, or Power BI appear in the same graph. Datadog builds lineage from the query history in the time window you choose, so widen the window to include jobs that run weekly or monthly.
Two common lineage workflows are:
- Root cause analysis. Anchor on a broken table or dashboard, set the downstream depth to 0, and step upstream. Tables flagged by a quality monitor show their status on the graph, so you can see where a problem starts.
- Impact analysis. Before you change or drop a column, anchor on it, set the downstream depth to the maximum, and switch to the List view to see every table and dashboard that depends on it.
Query analysis
Query analysis turns your Amazon Redshift query history into trends, so you can catch queries that slow down or scan more data over weeks and months, not just the last 7 days. Figure 5 shows the result for the last question: an INSERT run by the etl_svc user.
Figure 5: Query count, execution time, and data scanned for a normalized INSERT pattern
To explore query patterns:
- Choose Data Observability, then Queries, and choose Amazon Redshift.
- Review normalized query patterns. For each pattern, Datadog shows how often it runs, how long it takes, and how much data it scans.
- Group patterns by query, cluster, user, database, or statement type.
- Filter by the tables they read or write.
Because Datadog combines the query history from every connected cluster and workgroup, you can answer the following questions across your whole Amazon Redshift footprint:
- Which query patterns take the longest or read the most data?
- Which users or service accounts run the most expensive queries?
- Which queries write to
analytics.int_orders_enriched, and how has their runtime changed over time?
Quality monitoring
Quality monitors alert you when an Amazon Redshift table is not updated, changes unexpectedly in volume, or contains values that fall outside its normal range. Lineage then shows the upstream cause and the downstream impact.
Figure 6: An anomaly monitor on orders per hour in Datadog
Data Observability monitors track the following metrics:
- Freshness
- Row count
- Column-level metrics such as nullness and uniqueness
- Custom SQL metrics
Each monitor can use anomaly detection, which learns a metric’s trends and seasonality so that you don’t need to set a threshold for every table. Figure 6 shows an anomaly monitor on orders per hour, grouped by traffic source. When the metric falls outside its expected range, Datadog flags the likely upstream cause and the downstream assets at risk. Schema change monitors (currently in preview) alert when an Amazon Redshift table or column is added, removed, or renamed, or when a column type changes.
Lineage also helps you decide what to monitor. For example, add a relation filter to monitor every table upstream of a specific dashboard.
Quality monitoring runs aggregate queries in Amazon Redshift, such as COUNT(*) and MAX(<timestamp_column>), and sends only the resulting values to Datadog, not rows from your tables. To protect sensitive columns, you can use Amazon Redshift dynamic data masking.
Example: Trace a stale dashboard to its cause
The following steps show how these features work together when the revenue dashboard stops updating:
- A freshness monitor on
analytics.fct_ordersalerts in Slack that the table hasn’t updated since its usual 02:00 load. - On the Lineage page, you anchor on
fct_orders. The monitor on the upstream tablestaging.stg_ordersis healthy, so the source data arrived and the problem is in the step that buildsfct_orders. The graph also shows that the Tableau revenue dashboard depends onfct_orders. - On the Queries page, you filter to queries that write to
analytics.fct_orders. The nightlyINSERTpattern run by theetl_svcuser shows failed runs starting at 02:00. - You fix the job and, before you rerun it, use impact analysis to list the downstream tables and dashboards whose owners you notify.
Clean up
To stop writing system table data to S3 Tables, for a provisioned cluster, run the following command:
For an Amazon Redshift Serverless namespace, run the following command:
Before you run the preceding commands, ask your Datadog account team to switch the query history source back to the warehouse. Datadog then resumes collecting query history from your warehouse where it left off, so lineage and query analysis continue without a gap.
Disabling the integration stops new deliveries but keeps the data that was already written. Amazon Redshift doesn’t deliver system table data to S3 Tables while the integration is disabled, so your long-term record in S3 Tables won’t include that period. Re-enabling the integration doesn’t backfill that period, and after 7 days, Amazon Redshift no longer retains those queries in the warehouse either. To stop incurring storage charges, delete the tables. Deleting the tables permanently removes the retained data, and Amazon Redshift doesn’t recreate them automatically.
Conclusion
In this post, we showed how to configure Datadog Data Observability to read Amazon Redshift query history from Amazon S3 Tables. With this integration, you can:
- Retain query history beyond the 7-day in-cluster limit for auditing and compliance.
- Collect query history without adding load to your warehouses.
- Analyze lineage and query activity across all your clusters and workgroups in one place.
AWS and Datadog built this integration together so you can use Amazon Redshift system table data in your existing observability workflows.
If you’re new to Datadog, you can sign up for a free trial. If you have questions or suggestions, leave them in the comments.
Additional resources
- Amazon Redshift documentation: System table integration with Amazon S3 Tables
- Datadog documentation: Data Observability Overview
- Related post: Long-term system tables retention in Amazon Redshift with Amazon S3 Tables
About the authors
Detecting cross-cloud lateral movement with AWS Security Hub
Post Syndicated from Kyle Shields original https://aws.amazon.com/blogs/security/detecting-cross-cloud-lateral-movement-with-aws-security-hub/
Most organizations run a multicloud estate, and so do the attackers targeting them. An adversary who compromises an identity in one provider follows that identity wherever it leads, including across a federated trust into a second cloud service provider. The signals enumerating this scenario are rarely missing; the problem is that they live in separate consoles, in different schemas, owned by different teams. No one has visibility into the whole picture, so no one can decide what to fix first.
AWS Security Hub addresses prioritization and triage with exposure findings. Security Hub correlates reachability, blast radius, vulnerabilities, misconfigurations, and effective permissions, providing a strong correlation layer with an attack-path visualization, providing the context needed to generate risks from findings. That analysis now extends to Microsoft Azure. Security Hub records and analyzes your Azure resources with the same correlation engine used for Amazon Web Services (AWS) resources. The resulting details and meta-data land in the same console, ranked in the same queue, providing holistic, multicloud visibility into your security risks.
In this blog post, you learn how to configure the Azure integration for Security Hub and use exposure findings to prioritize attack paths across both clouds from one console. We follow a realistic scenario: a compromised identity that threatens both an Azure and an AWS environment through a shared, federated identity plane. We show you how the critical exposures along that path are presented as ranked findings that you can triage together, and we map each one to the MITRE ATT&CK framework. We also cover the prerequisites that teams commonly overlook.
Why prioritizing multicloud risk is difficult
Consider an organization whose Microsoft Entra ID tenant is federated into an AWS account, so identities in the tenant can assume an AWS role. This is an ordinary and intentional configuration used to avoid having to manage a second set of credentials. It also means the two clouds share an identity plane: a single compromised Entra identity is both an Azure threat and—through the federation—an AWS threat.
An attacker exploits this, but the defensive signals land in different places:
| Where the risk lives | Traditionally visible in | Owned by |
| Weak Entra identity controls: over-privileged identities, no multi-factor authentication (MFA), vulnerable conditional access policies (CAP) | Entra ID and Microsoft Defender for Cloud | Identity team |
| Internet-reachable Azure host with admin rights | Defender for Cloud | Azure platform team |
| Federated trust into AWS | AWS Identity and Access Management (IAM) | Cloud security team |
| Sensitive data and over-exposed resources in AWS | AWS security tooling | Cloud security team |
Each team sees one fragment, and in isolation each fragment appears low severity. You see the risk only when you correlate all of it together and discover the same identity plane ties the attack path together. Exposure findings provide that severity within AWS; extending it to Azure closes the multicloud visibility gap.
How the Azure integration works
You create the Azure connector in the AWS Management Console for Security Hub. It authenticates to your Entra ID tenant through an application registration, records and evaluates your Azure resource configurations, and streams Microsoft Defender for Cloud alerts and Entra ID audit logs through an Azure Event Hubs namespace. Your Azure resources then flow into the same correlation engine that analyzes signals from AWS Security Hub Cloud Security Posture Management (CSPM), Amazon Inspector, Amazon Macie, and Amazon GuardDuty. That engine produces two kinds of findings:
- Control findings against standards such as the CIS Microsoft Azure Foundations Benchmark.
- Exposure findings, which are ranked, attack-path findings that correlate traits such as reachability, effective permissions, and misconfiguration, with a severity based on how discoverable and exploitable the risk is.
Both use the Open Cybersecurity Schema Framework (OCSF) and appear in the same console as your AWS findings. However, one filtering detail matters: because Security Hub produces the finding, its top-level cloud.provider is AWS, while the evaluated resource carries resources[].provider = Azure. Filter on resources.provider to scope to a single cloud.
Prerequisites
To follow along with this post, you need:
- An AWS account with Security Hub enabled. If you use a delegated administrator account for Security Hub, create the connector there, in the AWS Region where you aggregate findings.
- An Entra ID tenant with a Microsoft Azure subscription. You need privileges in Azure to create an application registration, assign roles at the tenant root management group, and create a subscription-level diagnostic setting.
- The Azure CLI, authenticated to the target subscription with
az logincommand. - Activity log export. Azure resource recordings are change-driven and depend on activity logs reaching the event hub that the connector reads. The onboarding process assigns an Azure policy to create the required diagnostic setting, but it only remediates existing subscriptions after you create a remediation task. If the connector reports healthy status but resources never appear, run
az monitor diagnostic-settings subscription listto confirm the export exists, and create a remediation task if the list is empty.
Configuration
The following steps detail how to connect your Azure environment to Security Hub v2: Registering the Azure application, establishing federated identity credentials, and assigning the roles required for AWS to evaluate your Azure resources.
Step 1: Create the Azure connector in Security Hub
The first step in this configuration is to create the Azure connector in Security Hub. The connector establishes trust with your Azure tenant and defines which subscriptions and regions Security Hub v2 will evaluate.
- Open the Security Hub console and choose Integrations.
- Choose Create Azure connector.
- Enter your Azure Tenant ID and the Application (client) ID of the application registration you created for the integration.
- For Subscriptions and Regions, select all. Attack paths cross subscription and Region boundaries, so partial coverage leaves blind spots where a compromised identity can pivot unseen. Scope to specific IDs or Regions only when data-residency rules require it.
- Run the generated setup script in your Azure environment, then choose Create connector.
Include the global region scope. Controls that evaluate Entra ID and Microsoft Graph resources require it, and those identity exposures are central to this scenario. If you also create an Amazon Inspector or Security Hub CSPM connector for the same tenant, keep its subscriptions and regions consistent with this one.
Step 2: Verify the connector and its recording activity
Health status alone doesn’t tell you whether recording is flowing. Confirm both.
AWS Command Line interface (AWS CLI) command 1: Verify connector health and recording state
Step 3: Query exposure findings for Azure resources
Scope to Azure by filtering on the resource provider.
AWS CLI command 2: Retrieve exposure findings for Azure resources
Step 4 (optional): Add Amazon Inspector for Azure vulnerability scanning
To add vulnerability findings for Azure virtual machines (VMs), function apps, or container registry images, create an Amazon Inspector connector for the same tenant. VM scanning requires each target VM to have a system-assigned managed identity, which you can enforce with an Azure Policy. Figure 1 shows a correctly configured Azure integration inside Security Hub, with vulnerability management and posture management deployed.
Figure 1: Successful configuration of the Azure integration with Security Hub
Step 5: Prerequisites for Microsoft Azure
See the AWS documentation for the prerequisites for Microsoft Azure.
Walk-through: Prioritizing a cross-cloud attack path
In this example, the organization has one identity plane across two clouds, comprising a Microsoft Entra ID tenant with a federated trust into an AWS account. An adversary who compromises the right Entra identity gains an initial foothold in Azure and a path into AWS, because both clouds trust the same identity plane. The following sections trace that path. Each step is a real, high-severity exposure finding that Security Hub ranked on its own. The point of the walk-through is to demonstrate a real-life scenario and examine all findings in one unified security console.
Phase 1: A compromised identity (Azure)
ATT&CK: Phishing (T1566), Valid Accounts: Cloud Accounts (T1078.004)
The path begins with an Entra identity that is both over-privileged and unprotected. You’ll find this in the Security Hub console under Exposures, where Security Hub raises it as an identity exposure finding and maps the attack path stemming from it:
Potential Unauthorized Access: Azure RBAC user with administrative access has MFA disabled (high). It correlates the user, the role assignment that grants administrative access, and the organization.
The tenant’s authorization policies let an attacker broaden that foothold, and Security Hub CSPM reports each policy as a failed control (high): Microsoft Entra ID authorization policies should prohibit default users from registering applications…should restrict user consent for applications, and Azure authorization policies should restrict guest invitations to admin roles only. Each finding expands what a single compromised, non-privileged identity can do without an administrator.
Phase 2: Foothold and privilege escalation (Azure)
ATT&CK: Exploit Public-Facing Application (T1190), Valid Accounts: Cloud Accounts (T1078.004)
The tenant contains an internet-reachable VM whose network security group allows inbound from any address, and whose attached identity holds administrative rights over the subscription. Security Hub surfaces this under Exposures, correlating reachability and effective permissions into one finding that shows why it matters: anyone reaching the VM inherits admin control of the subscription.:
Potential Initial Access: Potentially internet reachable Azure virtual machine with open network security group has administrative access (high). It correlates the VM, the role assignment, the network security group, and the public IP address.
The finding’s analysis reads like an attack path. The resource “may be reachable from the public internet,” “overly permissive network security group (NSG) rules allow unintended inbound access,” and “the Owner or Contributor role grants extensive permissions… enabling a threat actor to escalate privileges.” Security Hub evaluates this from configuration and network-path modeling, so it surfaces whether or not the VM is running. Figure 2 shows the correlated attack path for that virtual machine.
Figure 2: An Azure attack-path exposure, analyzed by the same correlation engine as AWS exposures
The cross-cloud bridge: Federation into AWS
The tenant from Phases 1 and 2 is federated into the AWS account through an IAM SAML identity provider. As shown in Figure 2, a role trusts that provider and grants read access to every bucket in Amazon Simple Storage Service (Amazon S3). This trust is what expands the risk across clouds from the same adversary: a compromised Entra identity can assume this role and reach AWS data.
This one hop lives in IAM rather than in Security Hub. Security Hub doesn’t not raise a finding for a role that trusts your own federated identity provider. Confirming it is a normal investigative pivot: the role trusts a SAML identity provider that represents your Entra tenant, the same tenant whose exposures you triaged when you added Amazon Inspector in Step 4.
Figure 3: The federated trust that links the two clouds through a shared identity plane
Phase 3: The impact (AWS)
ATT&CK: Data from Cloud Storage (T1530), Transfer Data to Cloud Account (T1537)
On the AWS side, the correlation engine has already categorized the resources this identity can reach. Under Exposures in the Security Hub console, the sensitive-data objective surfaces this finding because that reachable set includes data at risk; a compromised identity could destroy it:
Potential Sensitive Data Destruction: S3 bucket has sensitive data and versioning disabled and Object Lock disabled and MFA delete disabled (high). A Macie finding, The S3 object contains personal information, is a contributing signal, and the control S3 general purpose buckets should be encrypted at rest with AWS KMS keys fails alongside it.
The same account carries related AWS attack-path exposures. Two examples are Potential Resource Hijacking: Internet reachable EC2 instance with open security group has software vulnerabilities with limited effective permissions and Potential Unauthorized Access: IAM user has weak password policies. In the exposure queue, these sit next to the Azure findings, ranked by the same severity model.
Prioritizing across both clouds in the console
Here is the operational benefit. An analyst is notified of generated exposure findings and opens the dashboard and filters to High severity. In one prioritized list, without switching tools or opening a ticket for another team, they see the Azure admin identity without MFA, the internet-reachable Azure VM with subscription-admin rights, and the AWS sensitive data exposure. Together, these show the full scope of what a single vector, sharing an identity plane, might target. The analyst confirms the connecting federation with one pivot into IAM. The multicloud triage that used to require two products and two teams now occurs in one place. Figure 4 shows that single ranked queue.
Figure 4: Cross-cloud exposure prioritization in a single console
Phase-to-exposure summary
The following table traces each phase of the attack path to its MITRE ATT&CK techniques, the cloud where it plays out, and the ranked Security Hub exposure that surfaces it — following the pivot from Azure into AWS across the shared identity plane.
| Phase | ATT&CK | Cloud | Ranked exposure in Security Hub |
| 1. Compromised identity | T1566, T1078.004 | Azure | Potential Unauthorized Access: Azure RBAC user with administrative access has MFA disabled (High) |
| 2. Foothold and privilege escalation | T1190, T1078.004 | Azure | Potential Initial Access: internet reachable Azure VM with open NSG has administrative access (High) |
| 2.1 Bridge | T1550 (Use Alternate Authentication Material) | Azure to AWS | Federated trust, confirmed in AWS IAM (shared identity plane) |
| 3. Data objective | T1530, T1537 | AWS | Potential Sensitive Data Destruction: S3 bucket has sensitive data… (High), plus Macie |
Conclusion
A cross-cloud attack is difficult to prioritize because signals are generated across separate consoles, schemas, and teams. In this post, you saw how the Azure integration for AWS Security Hub brings Azure resources into the same exposure engine and the same queue as your AWS resources. One analyst can prioritize an attack path that spans a compromised Microsoft Entra ID identity, across a federated trust, to sensitive data in Amazon S3, without leaving Security Hub.
To recap why this workflow is practical and effective:
- Security Hub records and analyzes your Azure security findings and displays them in the same unified console as your AWS resources, and produces ranked, attack-path exposure findings for both clouds.
- Findings from both clouds share the OCSF schema, so you filter, group, and prioritize them in one place. Filter on
resources.providerto scope an individual cloud. - Security Hub correlates signals into attack paths within each cloud. The analysis creates a cross-cloud narrative, such as a shared federated identity plane, while co-locating ranked correlation findings across both Azure and AWS, creating efficient scoping and remediations.
- Confirm your prerequisites. Include the global region scope for Entra ID controls, know that sign-in log signals require an Entra ID P1 or P2 license, and confirm that the subscription diagnostic setting that exports Activity Logs to the connector’s event hub is in place. A connector can report a healthy status while it records nothing.
To get started, see Enabling Microsoft Azure integration in Security Hub and Exposure findings in Security Hub.
If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.
Raphael Warnock: Congress Must Reassert Its Authority
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/-tu4e4iUUHE
An updated Clairic and Clairic-flash are now open-weight, from the new Workers AI Superintelligence team
Post Syndicated from Alex Reneau original https://blog.cloudflare.com/open-clairic/
Cloudflare has become a neolab. We’re building our own frontier AI models for our customers and the open-source community.
Today, we’re announcing two open-weight model releases:
- We’re introducing an updated version of Clairic. Since the preview, we’ve improved extraction from complex documents including images and PDFs (new!), with more reliable handling of tables, lists, and dates, and better grounding of answers in the source material.
- We’re introducing Clairic-flash, a lighter, faster version of Clairic that delivers strong extraction and prediction performance in a compact, 9-billion-parameter model.
Both extraction models are hosted on Workers AI and full open weights are available on Hugging Face.
We’re also excited to re-introduce ourselves as the Workers AI superintelligence team, the frontier AI research team behind Clef, Clairic, and lots more in the works. This team is working quickly to push the AI frontier and build useful models for Cloudflare’s customers and the open source community.
A new version of Clairic: redesigned after the preview release
Since announcing Clairic in preview, we have received a ton of use cases and helpful feedback on how customers wanted to use an extraction model. We heard about use cases ranging from extracting data from images like receipts to reading values from support tickets. We knew that we wanted extraction to be the clear focus for the model, so it had to excel at reading from unstructured data.
We decided to go back to the drawing board with Clairic and redesigned our architecture, differentiating this new version of Clairic from our preview release. For ordinary text and number extraction fields, we now use parallel slot autoregressive generation instead of a single forward pass. Each field uses the tokens it has already written to choose its next token, then stops at its own end marker. All the fields advance together in the serving batch, still giving lightning-fast latency per request. This boosted our accuracy in extraction for both text and images, and the trade-off in accuracy offsets the small latency cost. For computation, estimation, and extraction use cases, we trained special heads that can handle estimates, forecasts, durations, calculated dates, and explicit arithmetic.
Although the model architecture evolved, we kept the parts of the typed API interface that make the answers useful: confidence scores, character spans, and probabilities are still intact with every request. The model is still incredibly fast and cheap. From the evals below, you can see how our newer versions of Clairic have greatly improved on extraction across text, images, PDFs, and more.
|
Eval |
Clairic-preview |
Clairic |
Clairic-flash |
D1.2 + OCR |
ScaleDown |
|
Fresh text fields, 96 requests |
295/336 |
335/336 |
328/336 |
304/336 |
259/336 |
|
Internal eval (mchen) – mixed-input fields, 36 requests |
207/226 |
221/226 |
213/226 |
116/226 |
156/226 |
|
Tracked customer assertions, 139 request shapes |
1,033/1,263 |
1,263/1,263 |
1,263/1,263 |
973/1,263 |
653/1,263 |
|
Synthetic receipt fields in text and images |
369/576 |
576/576 |
576/576 |
397/576 |
280/576 |
There are no public extraction benchmarks yet, but we ran our internal evals for other emerging extraction models on the market, such as Liquid AI’s D1.2 (pipelined with Apple Vision for optical character recognition) and Scaledown’s Extract. Our Clairic models excel across extraction use cases, but take these evals as directional guidance since they are self-reported. We wanted to show an illustrative picture of how Clairic is performing across generalized extraction use cases and celebrate the fact that other companies are releasing extraction models as well — confirming our original hypothesis that extraction was a pain point for LLM users because of the cost, latency, and accuracy.
But is it fast?
We ran latency tests for Clairic and Clairic-flash, measuring complete HTTP response from a self-hosted server, including all fields in the request. Even with the redesigned architecture, you can expect responses in under one second — much faster than typical LLM responses for similar workloads.
|
Eval set |
Requests per model |
Clairic p50 / p95 |
Clairic-flash p50 / p95 |
|
Fresh text fields |
96 |
358 / 736 ms |
155 / 328 ms |
|
Fresh image fields |
48 |
453 / 976 ms |
305 / 605 ms |
|
Commercial leases |
180 |
691 / 803 ms |
379 / 519 ms |
|
Loan pricing |
600 |
395 / 407 ms |
188 / 192 ms |
|
Traffic forecasting |
114 |
532 / 585 ms |
243 / 261 ms |
|
Expense audit, development |
60 |
632 / 742 ms |
393 / 512 ms |
Better extraction for images and PDFs
In our preview blog post, Clairic read a photo of a receipt. Now the Clairic family of models can read PDFs too, so you can ask for the supplier, line items, and total in one request, even when they appear on different pages. You can include up to four images or PDF pages in total, and line items can come back as rows that keep each description, quantity, and price together. Due to Clairic’s new architecture, image reading accuracy has improved from 207 errors to 0 on our internal benchmarks, explicitly covering text and images.
Promotional pricing on Clairic for a limited time
When we first launched our preview endpoint of Clairic at @cf/cloudflare/clairic, we hosted the 9B variant as it was faster and easier to train, at the preview price of $0.10 per M input tokens. We’re now moving the 9B model to the @cf/cloudflare/clairic-flash endpoint and the 27B model will live at @cf/cloudflare/clairic.
The 27B Clairic model will be priced at $0.24 per M input tokens, while the 9B Clairic-flash model will be priced at $0.10 per M input tokens. Although the model does technically generate output tokens, we decided to keep the System One pricing principles and are only charging on input tokens: we eat the cost of the output token generation.
In order to make this a seamless swap, we’re offering a promotional discount on Clairic — until December 1, 2026, both Clairic and Clairic-flash will cost $0.10 per M input tokens. This means you get to try out the higher quality variant of Clairic at the same price. If your applications are hooked up to the Clairic endpoint that we released in preview, you will automatically benefit from the better extraction capabilities of our new model, which we’re rolling out in place.
If you’d like to move more cost-sensitive workloads to the cheaper 9B Clairic-flash variant, we encourage you to do so. On December 1, we’ll be ending the promotional discount for Clairic and pricing will resume at $0.24 per M input tokens instead of the discounted $0.10 per M input tokens.
Clairic and Clairic-flash (new) are open-weight
Both Clairic models are now open-weight on Hugging Face as well. We have seen an outpouring of experiments and tuned models from our release of Clef, and we’re happy to continue supporting teams and research with our open-weight release of Clairic.
Our mission with these System One models is to help people augment their expensive LLM usage with smaller, faster, cheaper models that are purpose-built for a specific task. We hope that releasing these models open-weight encourages others to experiment and build on our ideas as well.
Try them out
Clairic and Clairic-flash are available on Workers AI as @cf/cloudflare/clairic and @cf/cloudflare/clairic-flash. The developer documentation has the full API schemas, which remain unchanged from our preview endpoint. We’re also publishing the open-weight releases for Clairic and Clairic-flash on Hugging Face.
The team behind these models — the Workers AI superintelligence team — is just getting started, and growing fast to push frontier AI research at Cloudflare. Join us early and help shape what the superintelligence team becomes.